ViT-Cap: A Novel Vision Transformer-Based Capsule Network Model for Finger Vein Recognition


Abstract
1. Introduction
- (1)
- The model can encode long-range dependencies in images and can better understand the relationship between advanced semantic visual information and basic visual elements in finger vein images.
- (2)
- Based on the vision transformer, we introduced the local information shared by the capsule network module and constructed a finger vein recognition model based on global attention and local attention, which better obtained the features of finger veins and maximized the performance of the model.
- (3)
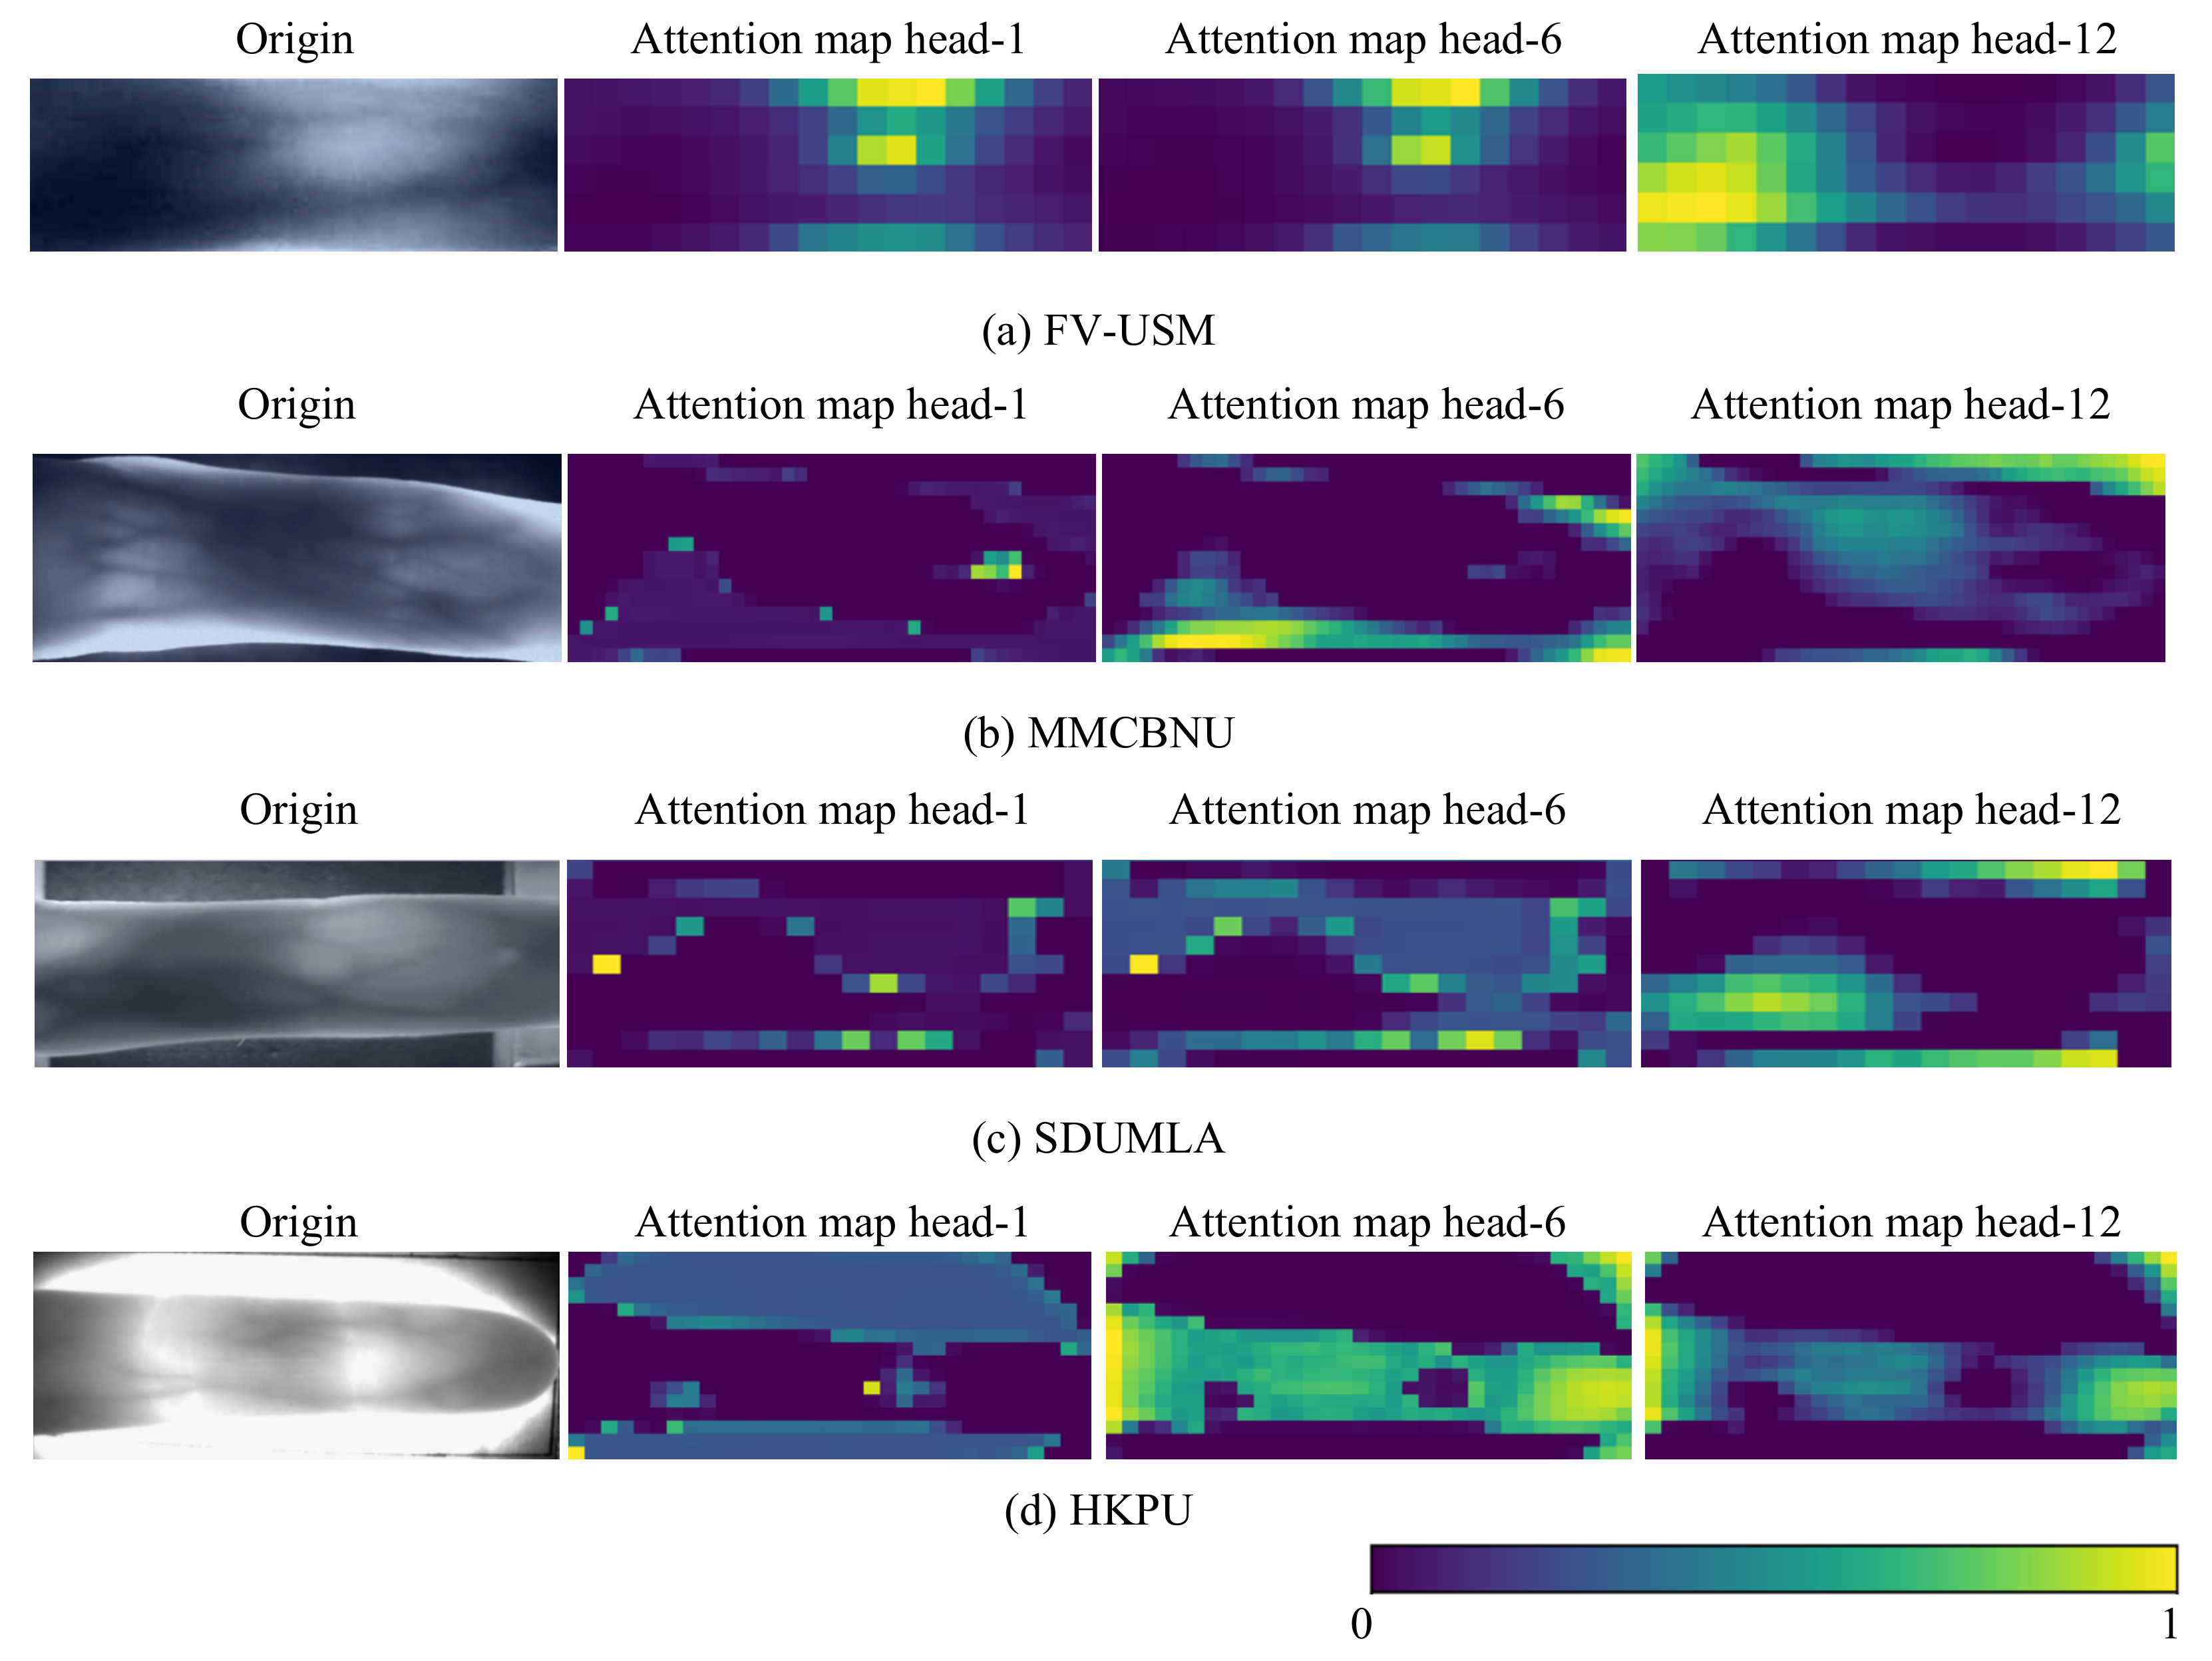
- Compared with CNNs, the model we proposed has higher logical interpretability, and we visualized part of the training process of the model. At the same time, due to the dynamic routing mechanism in the model, better performance was obtained when processing small-scale image data, which solved the limitation of a small amount of finger vein data.
2. Related Work
3. Materials and Methods
3.1. Motivation
3.1.1. Overview of Vision Transformer
3.1.2. Overview of Capsule Network
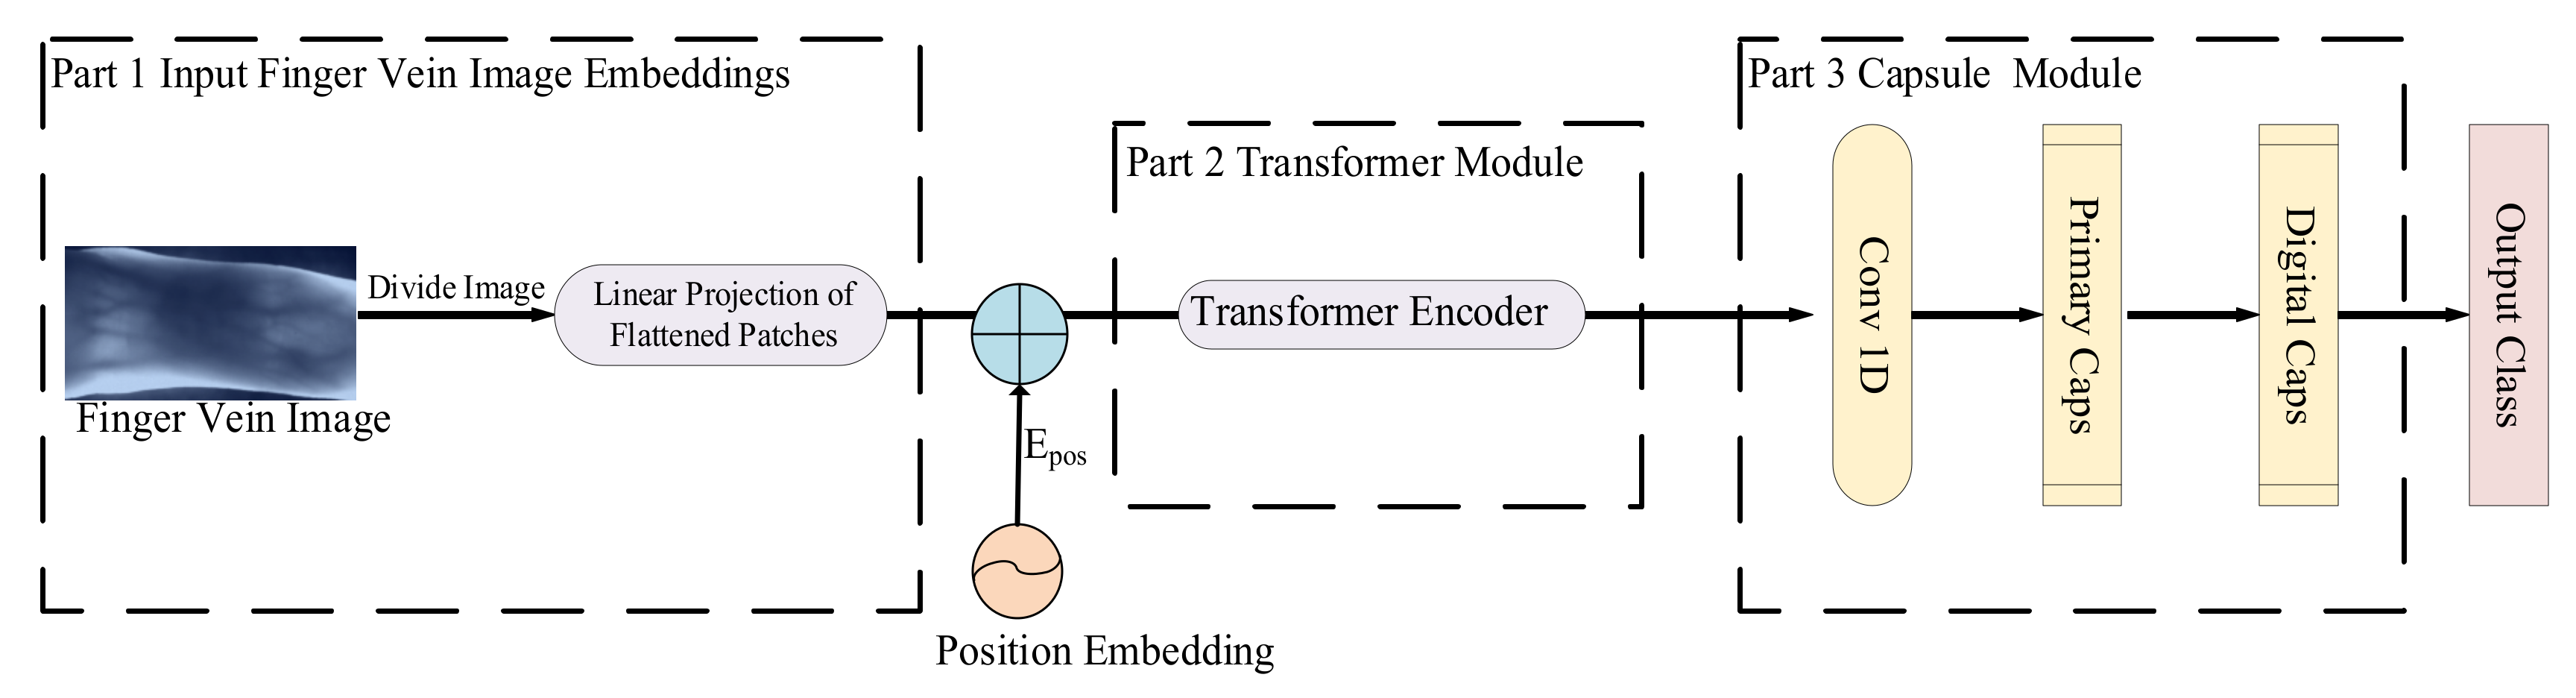
3.1.3. Overview of ViT-Cap Module
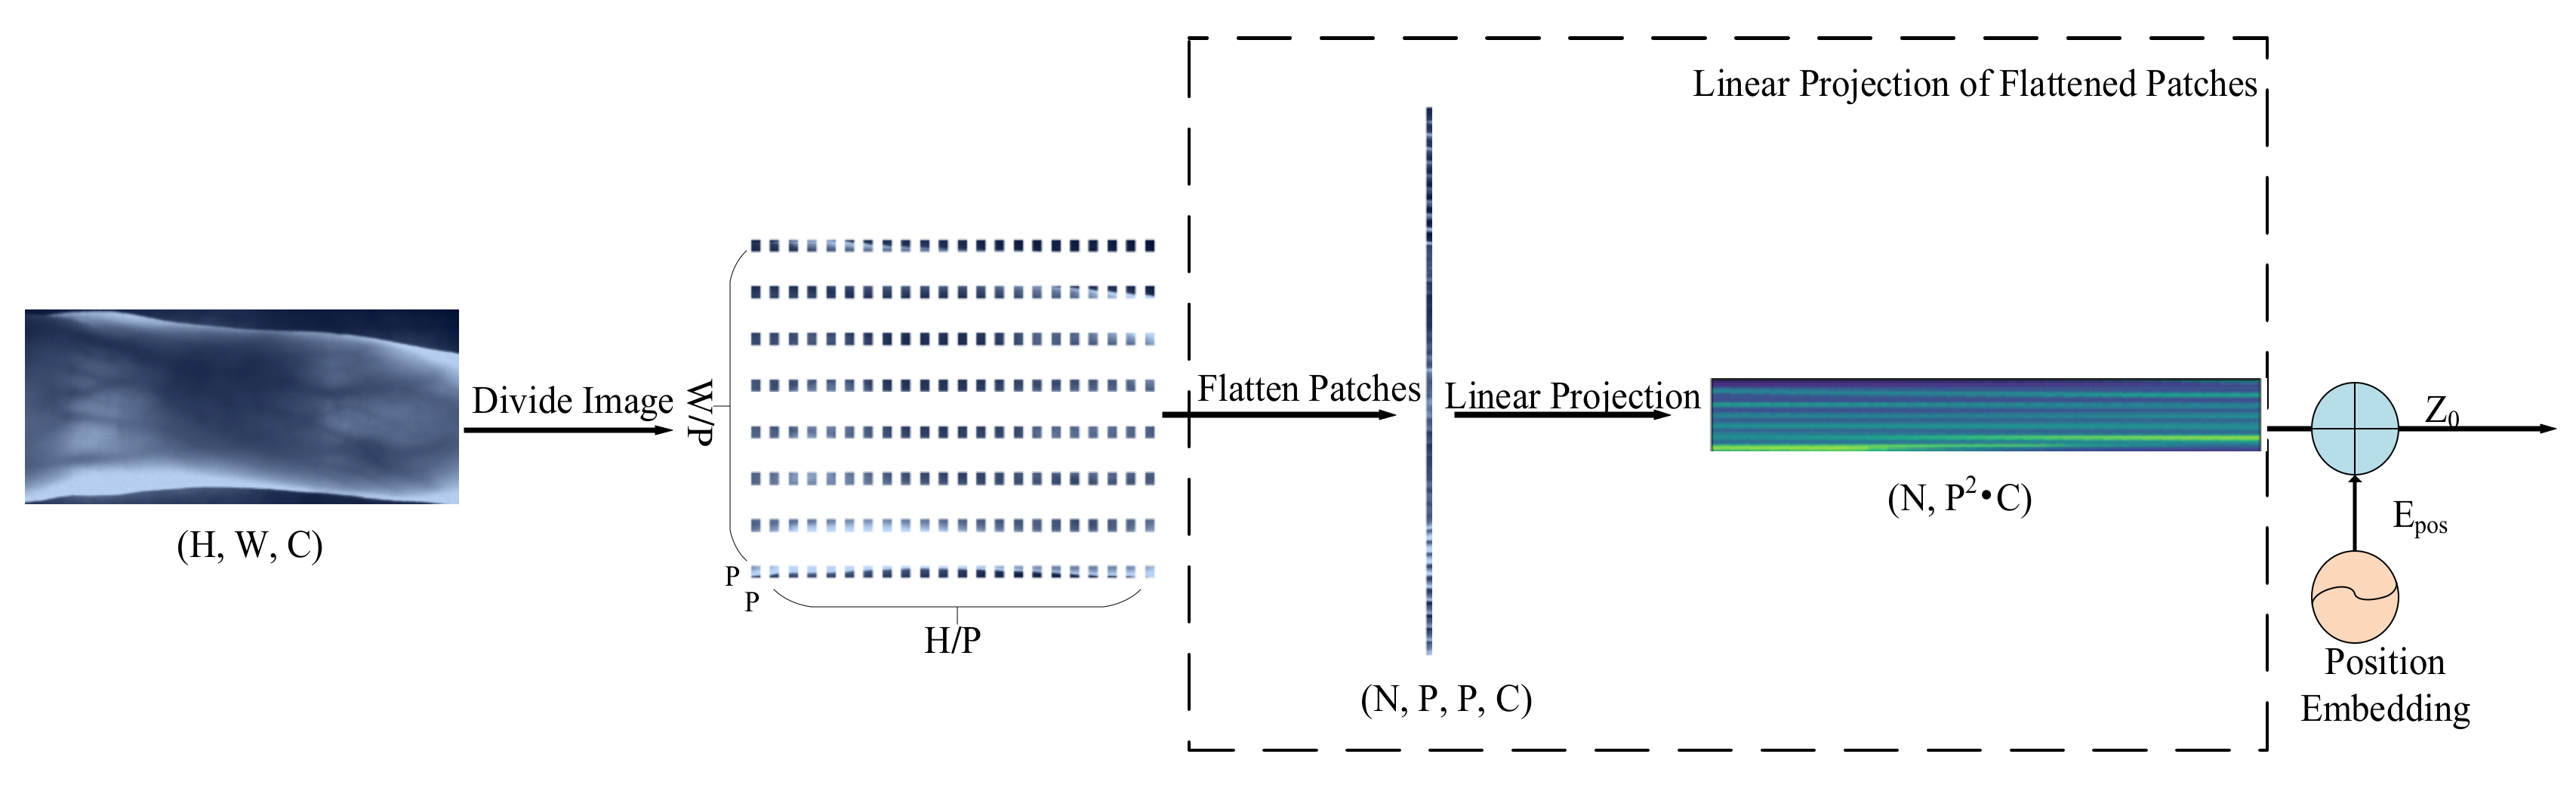
3.2. Linear Embedding of Finger Vein Images
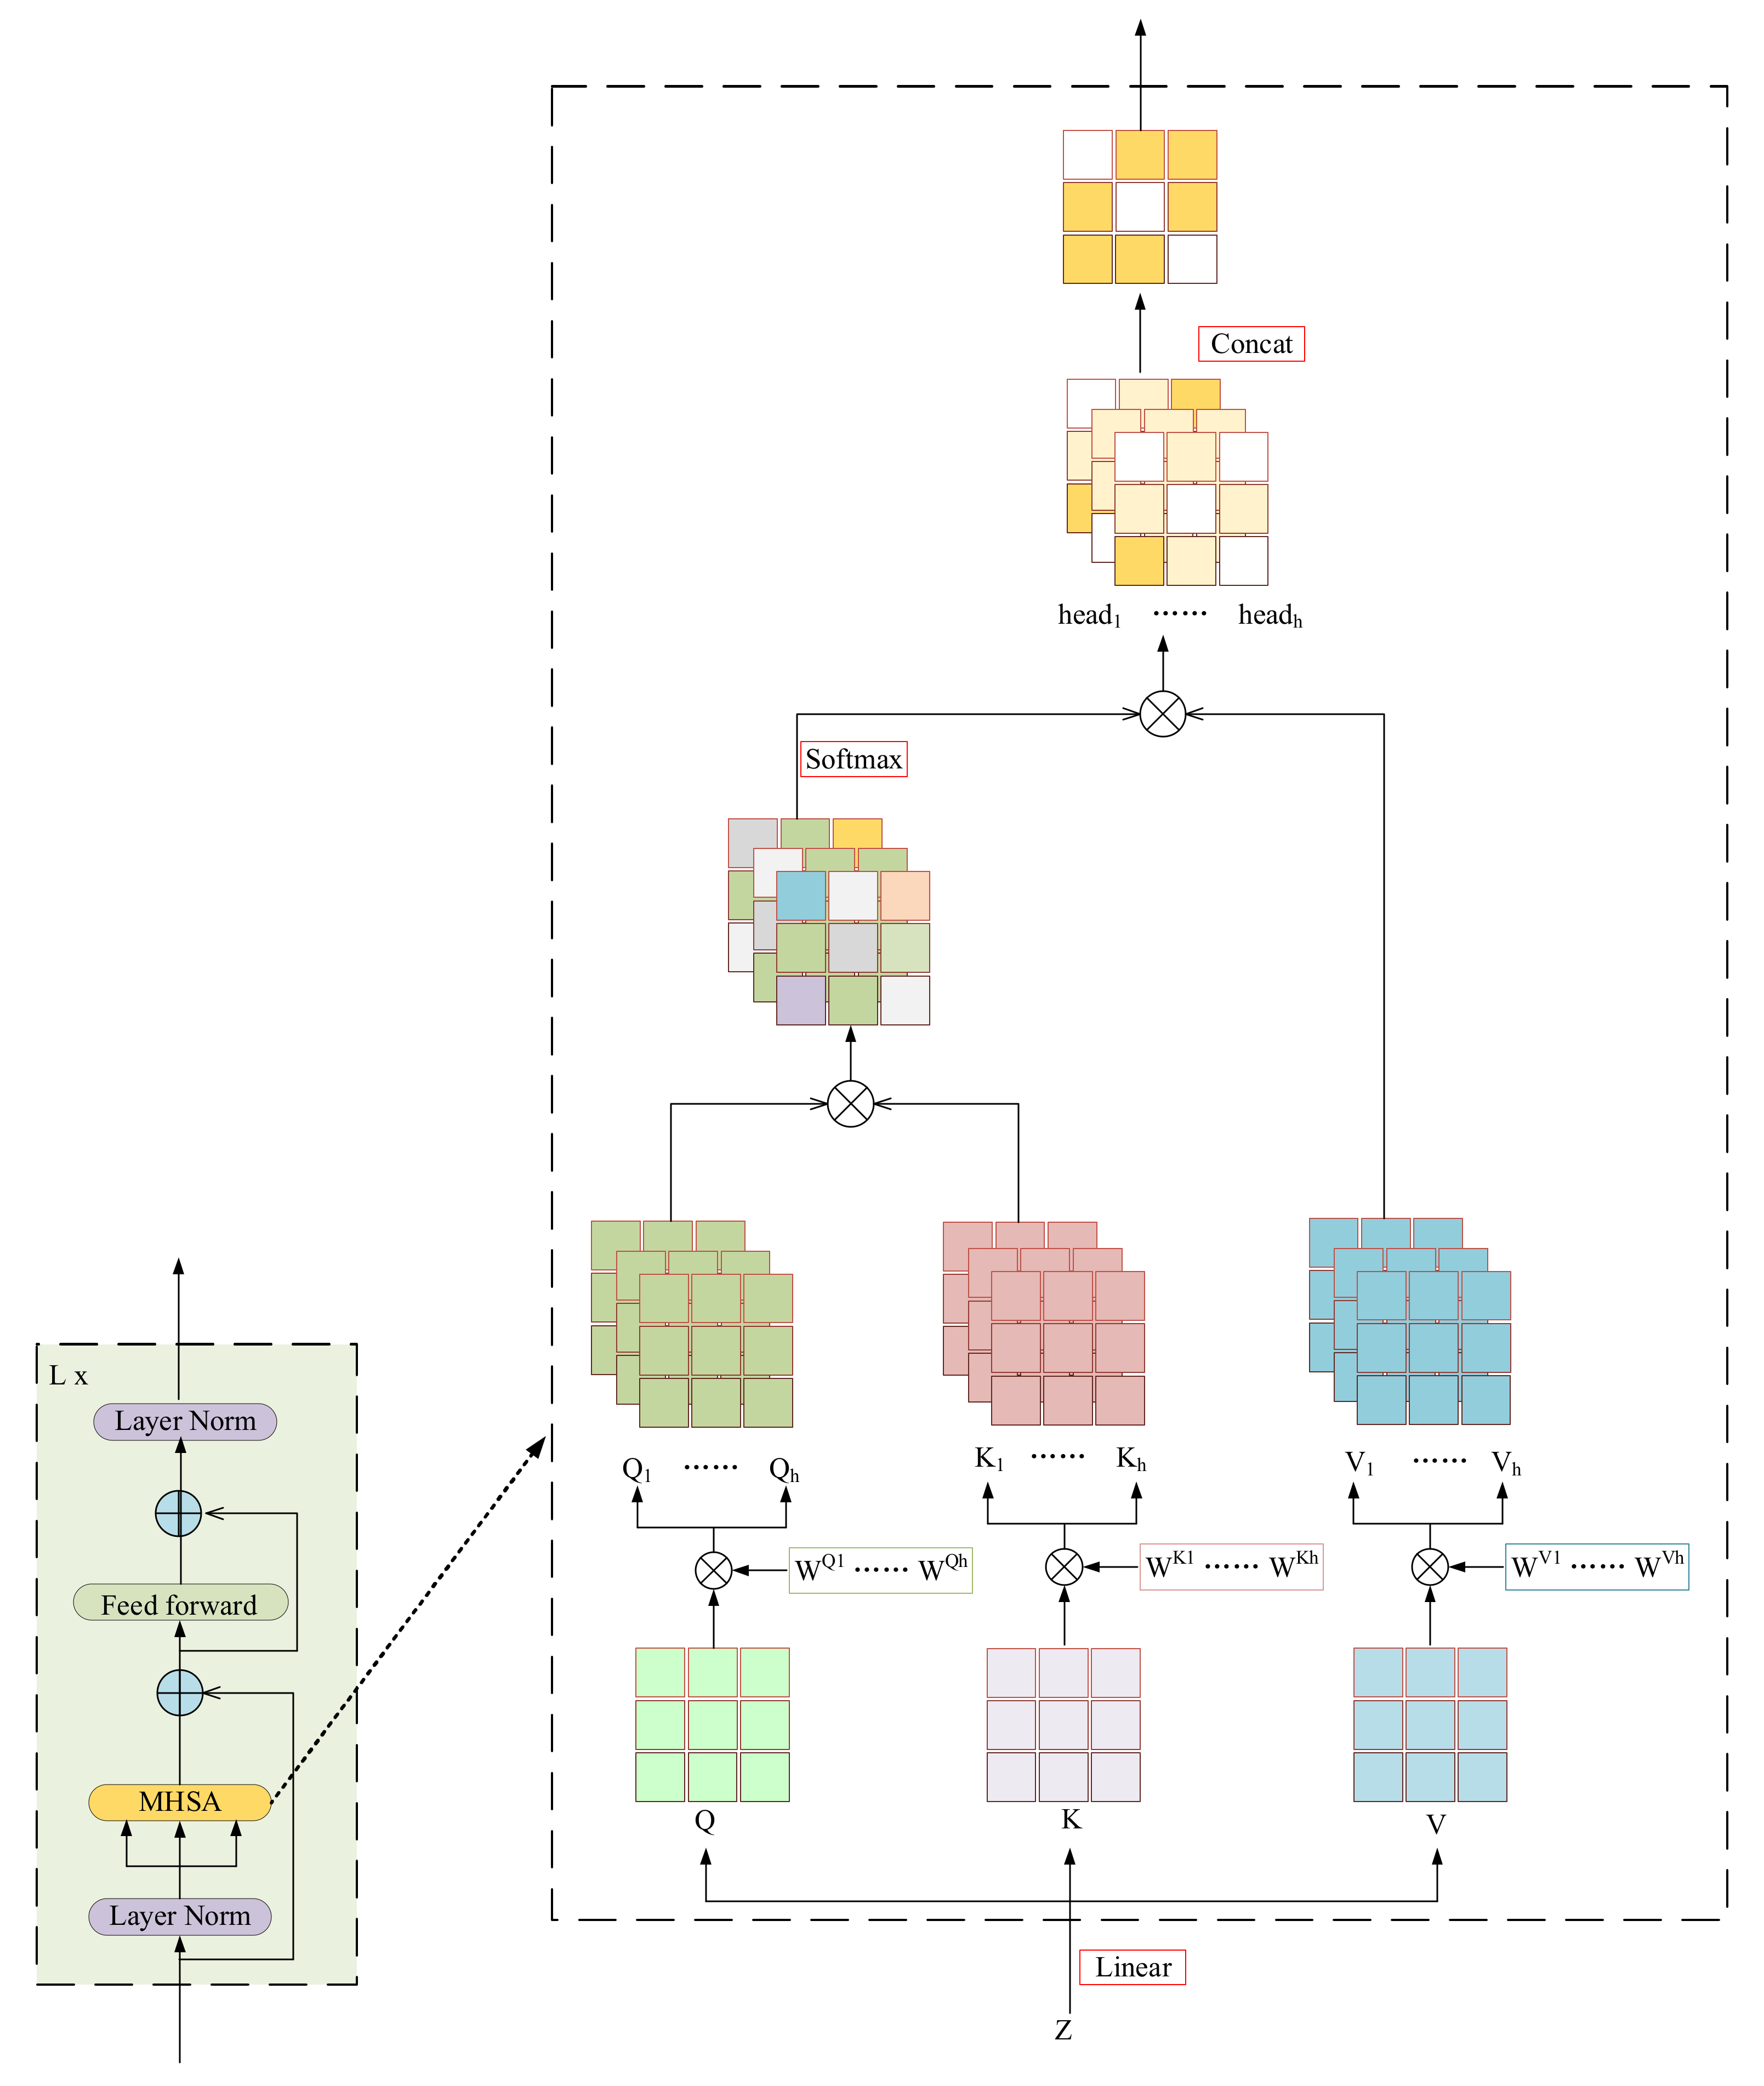
3.3. Transformer-Based Module
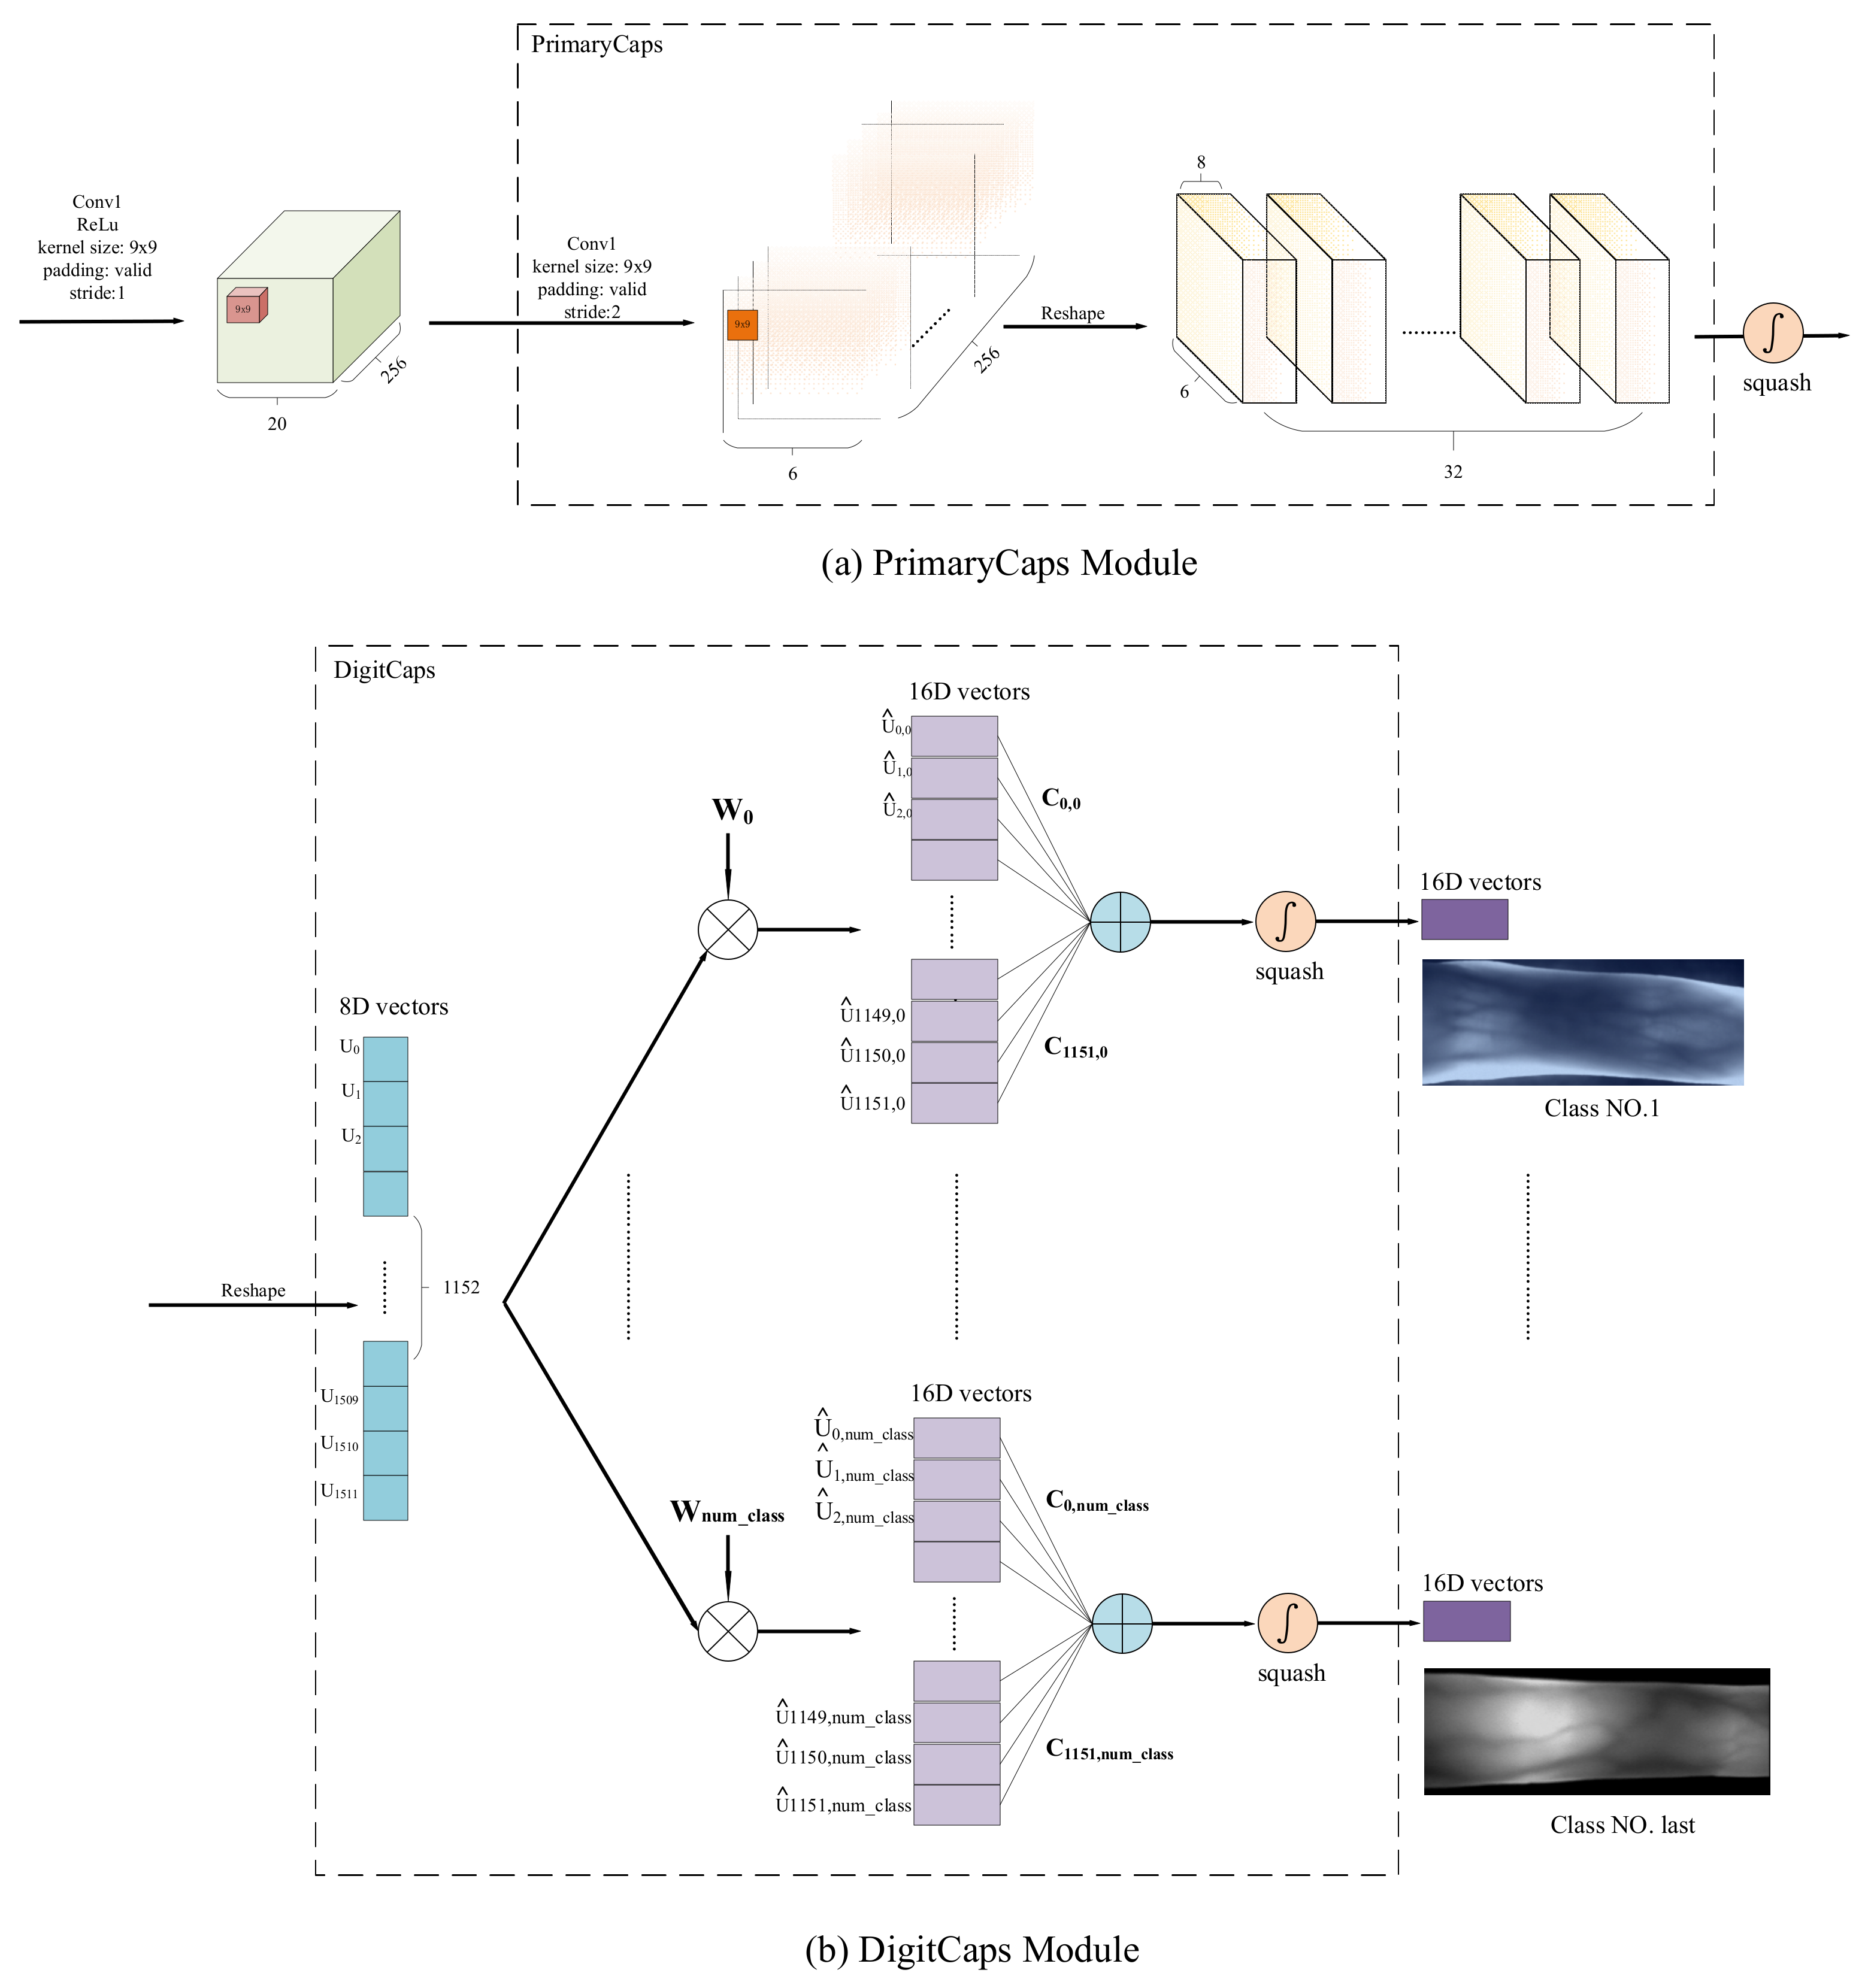
3.4. Capsule Network-Based Module
4. Results
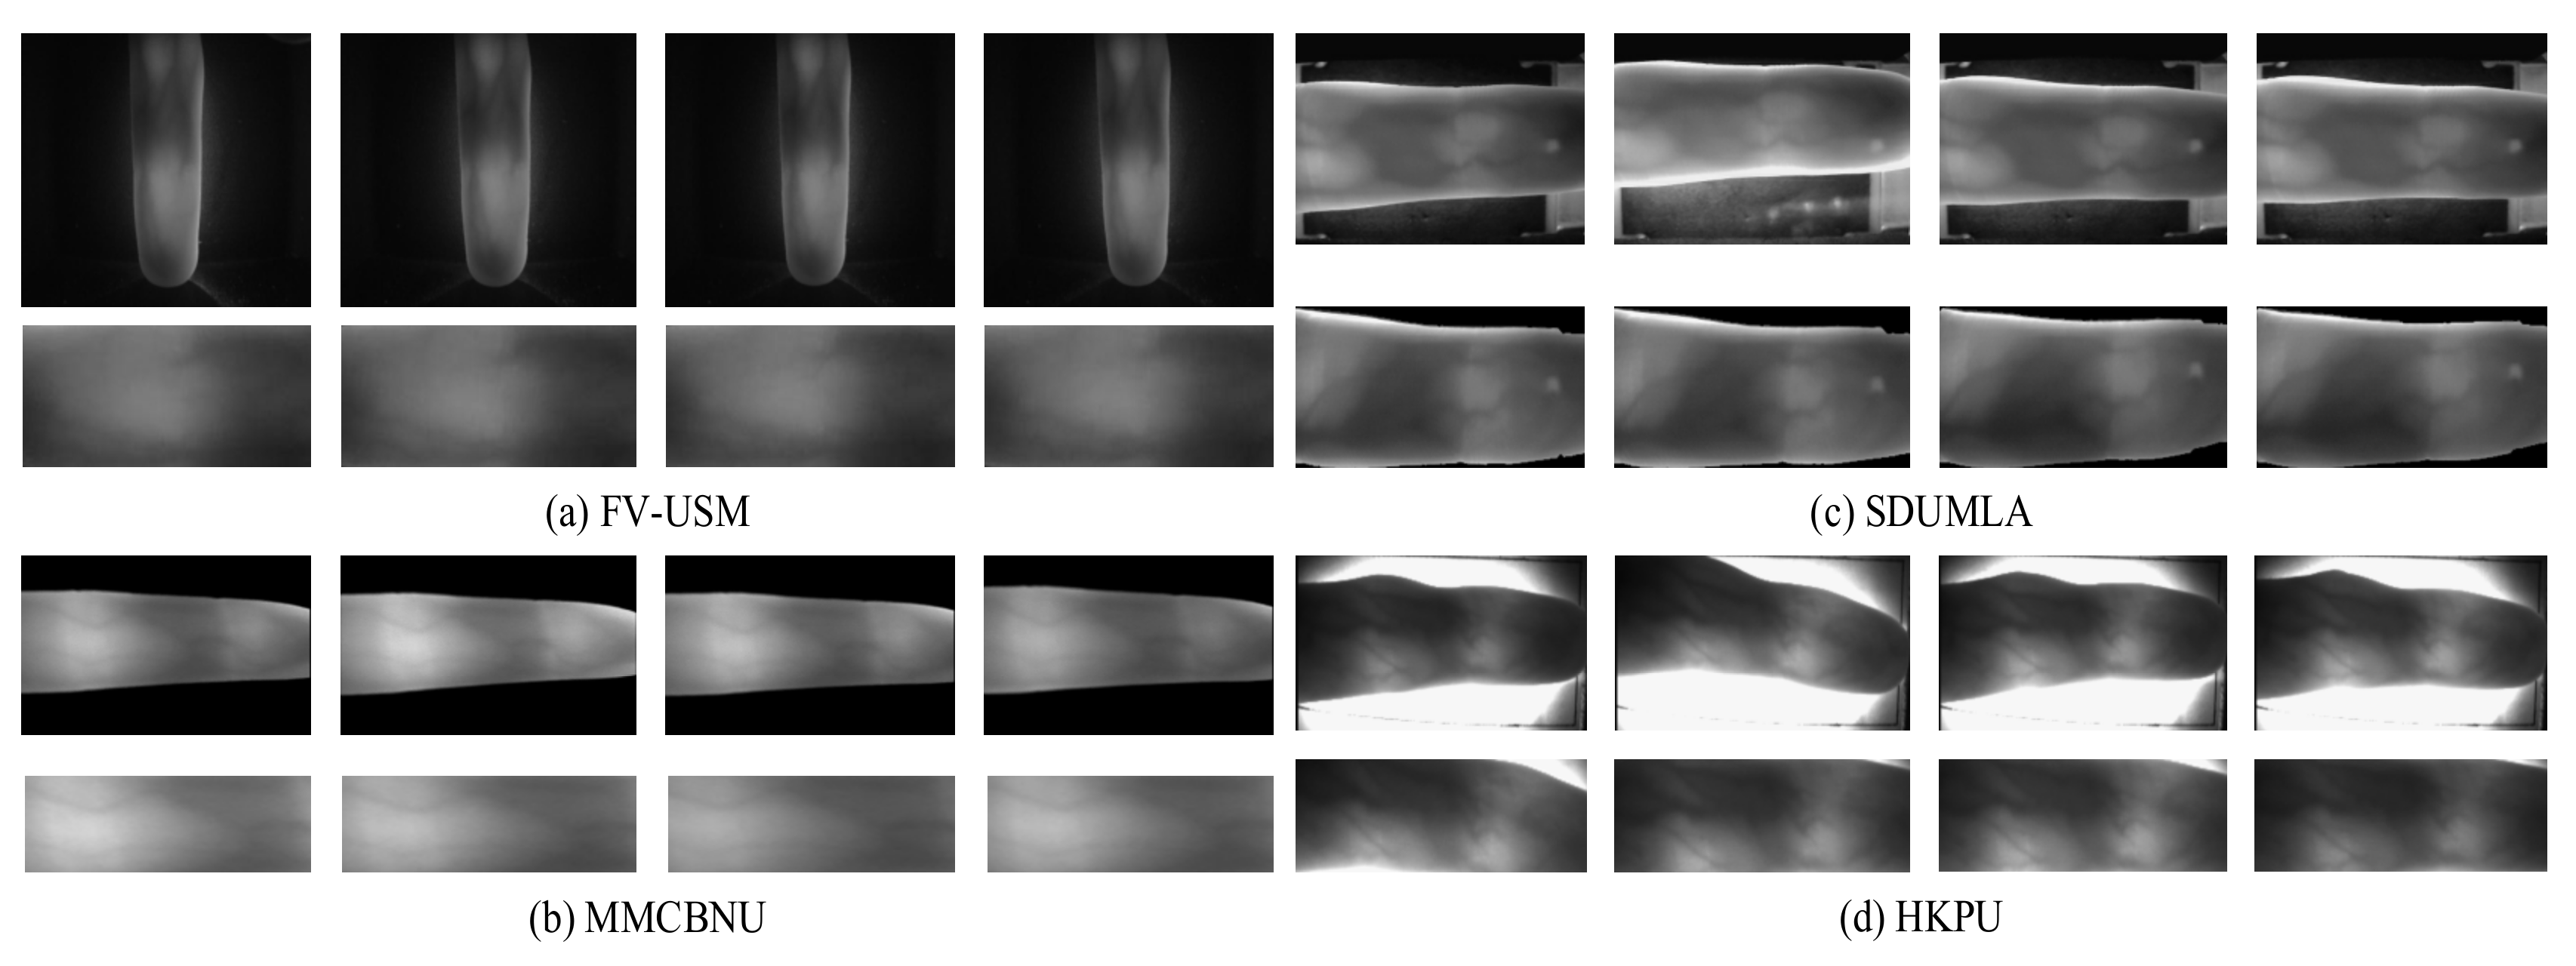
4.1. Finger Vein Datasets Description
4.2. Finger Vein Image Pre-Processing
4.3. Experimental Setup for Finger-Vein Recognition
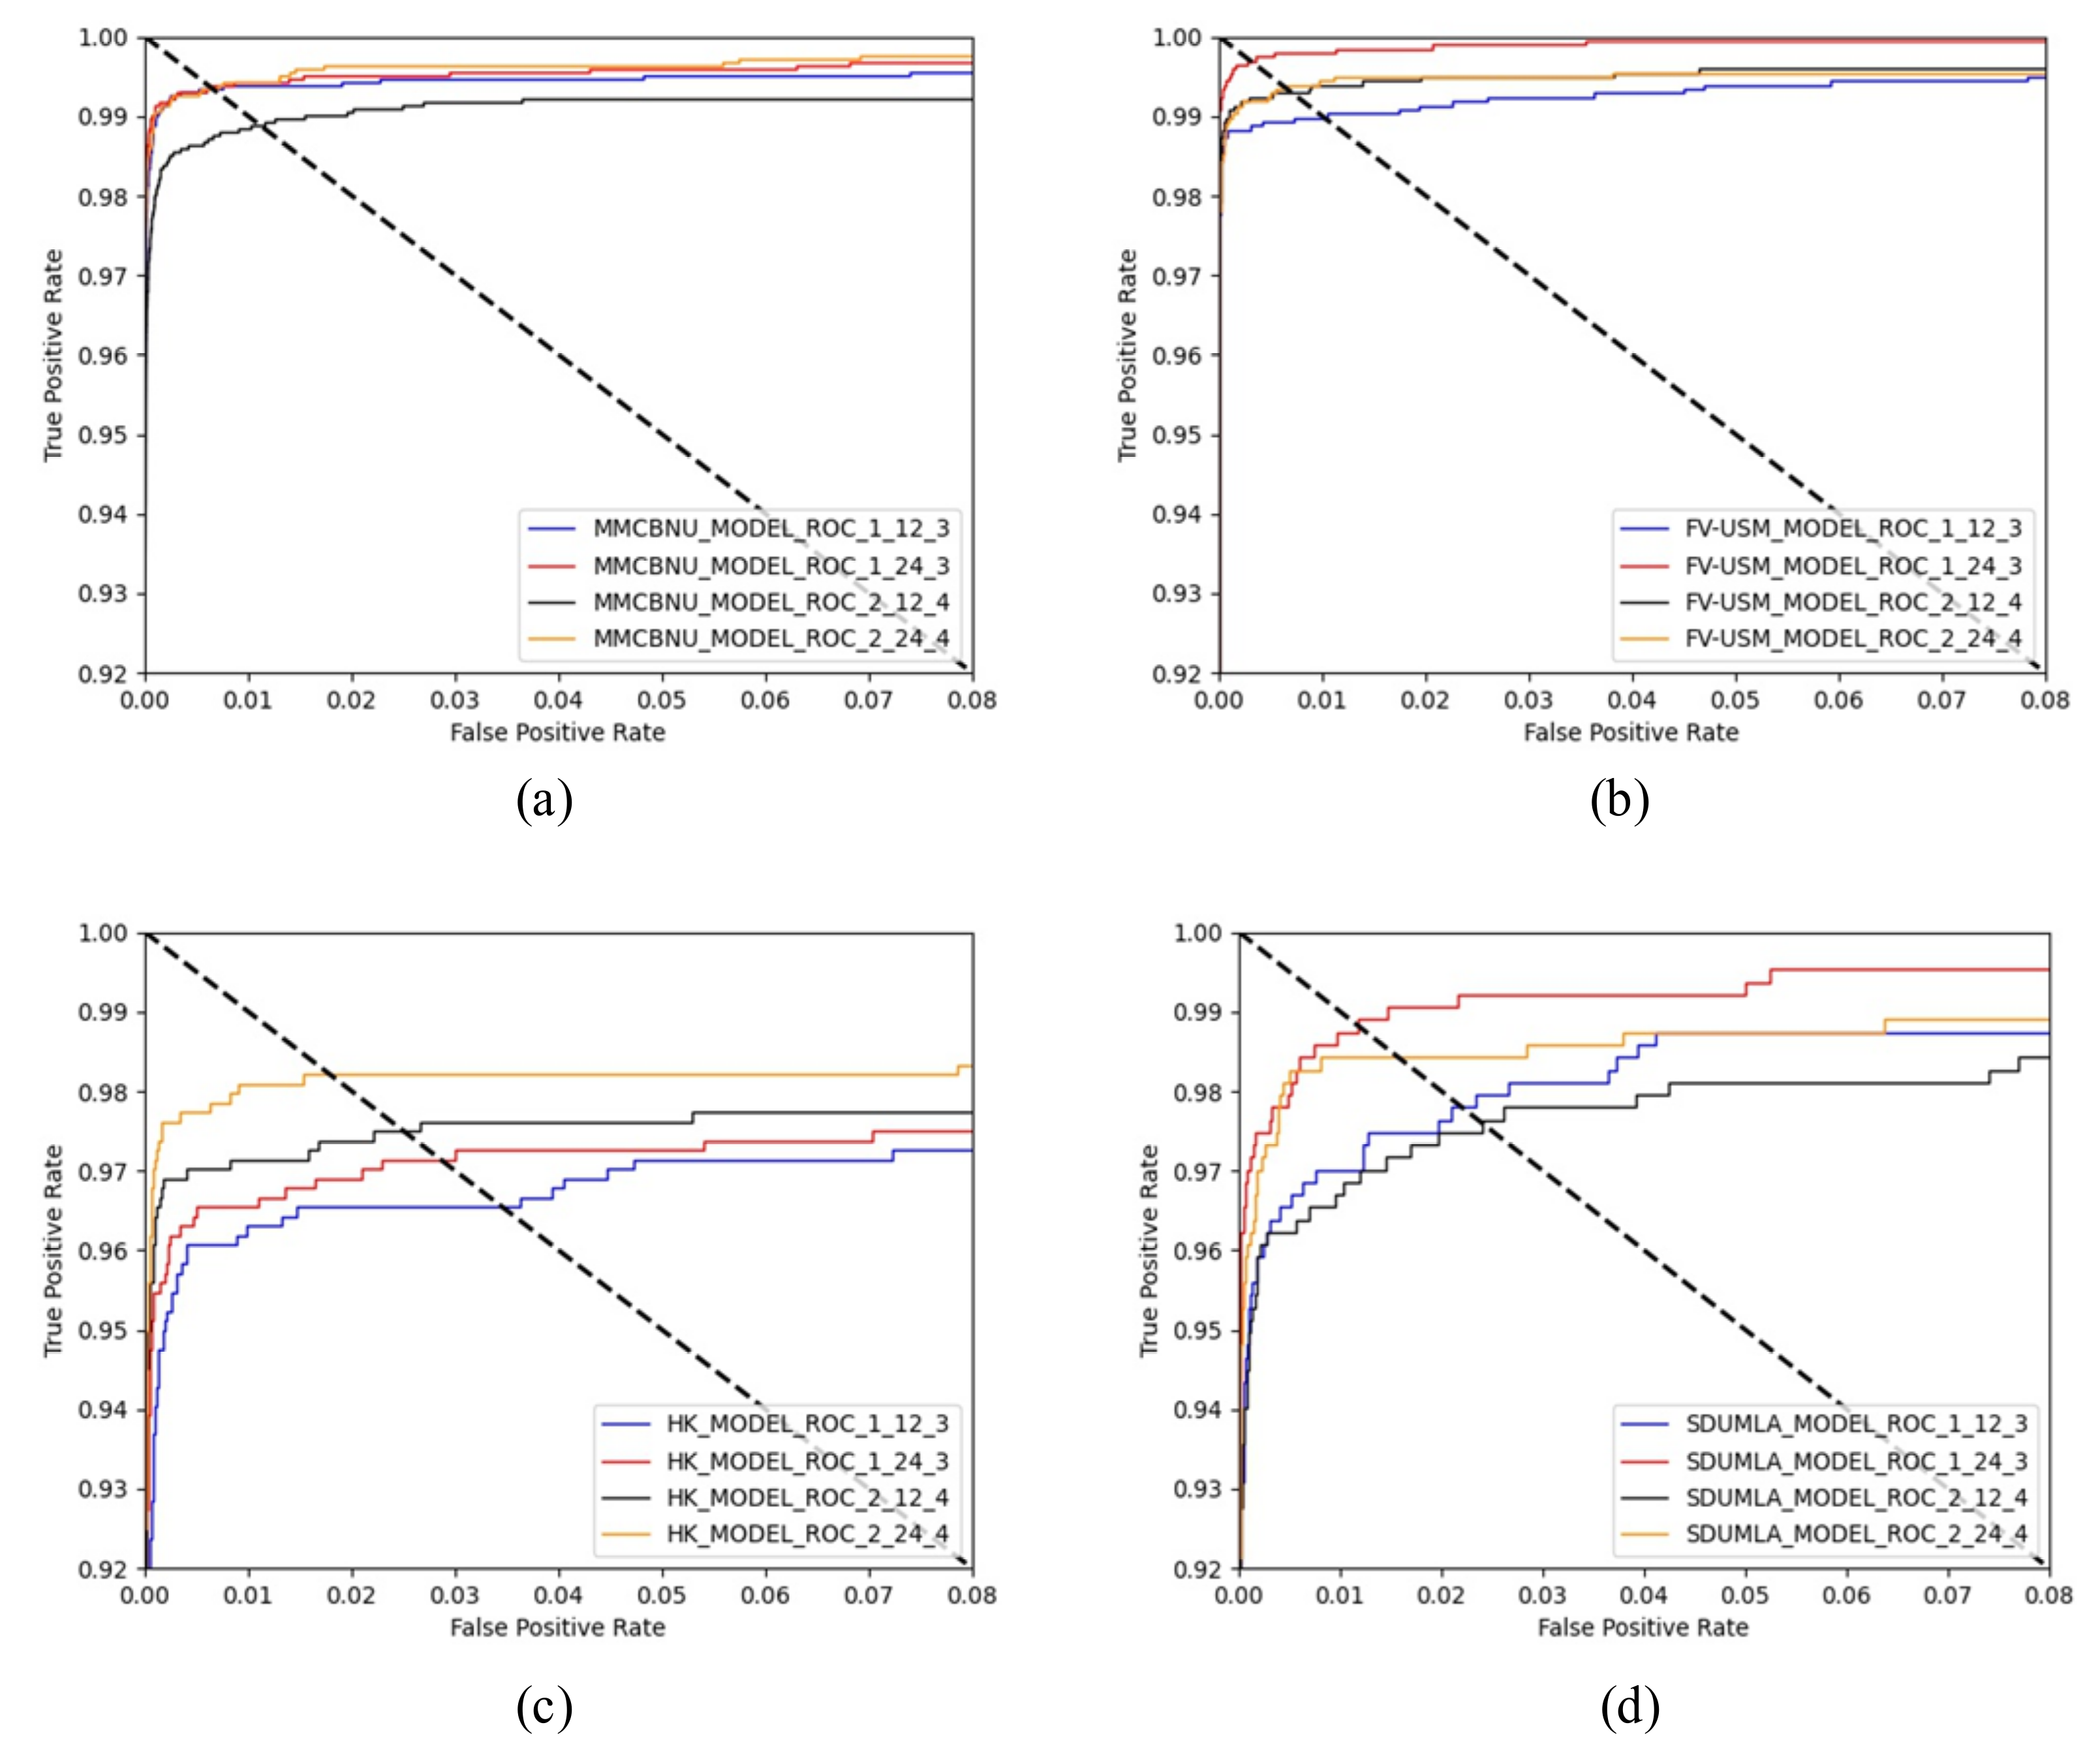
4.4. Experiment 1: Preliminary Analysis
4.5. Experiment 2: Comparison with State-of-the-Art Finger Vein Recognition Algorithms
4.6. Experiment 3: Performance Analysis of algorithms on Small Sample and Small Categories of Finger Vein Datasets
5. Conclusions
Author Contributions
Funding
Institutional Review Board Statement
Informed Consent Statement
Data Availability Statement
Conflicts of Interest
References
- Zhong, Y.; Deng, W.; Hu, J.; Zhao, D.; Li, X.; Wen, D. Sface: Sigmoid-constrained hypersphere loss for robust face recognition. IEEE Trans. Image Process. 2021, 30, 2587–2598. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wang, K.; Kumar, A. Periocular-assisted multi-feature collaboration for dynamic iris recognition. IEEE Trans. Inf. Forensics Secur. 2021, 16, 866–879. [Google Scholar] [CrossRef] [Scilit]
- Liu, F.; Liu, G.J.; Zhao, Q.J.; Shen, L.L. Robust and high-security fingerprint recognition system using optical coherence tomography. Neurocomputing 2020, 402, 14–28. [Google Scholar] [CrossRef] [Scilit]
- Ma, H.; Hu, N.; Fang, C.X. The biometric recognition system based on near-infrared finger vein image. Infrared Phys. Technol. 2021, 116, 103734. [Google Scholar] [CrossRef] [Scilit]
- Jin, J.; Di, S.; Li, W.; Sun, X.; Wang, X. Finger vein recognition algorithm under reduced field of view. IET Image Process. 2020, 15, 947–955. [Google Scholar] [CrossRef] [Scilit]
- Yang, L.; Yang, G.; Xi, X.; Su, K.; Chen, Q.; Yin, Y. Finger vein code: From indexing to matching. IEEE Trans. Inf. Forensics Secur. 2019, 14, 1210–1223. [Google Scholar] [CrossRef] [Scilit]
- Kumar, A.; Zhou, Y.B. Human identification using finger images. IEEE Trans. Image Process. 2012, 21, 2228–2244. [Google Scholar] [CrossRef] [Scilit]
- Shaheed, K.; Liu, H.; Yang, G.; Qureshi, I.; Gou, J.; Yin, Y. A systematic review of finger vein recognition techniques. Information 2018, 9, 213. [Google Scholar] [CrossRef] [Scilit]
- Das, R.; Piciucco, E.; Maiorana, E.; Campisi, P. Convolutional neural network for finger-vein-based biometric identification. IEEE Trans. Inf. Forensics Secur. 2019, 14, 360–373. [Google Scholar] [CrossRef] [Scilit]
- Wang, G.Q.; Sun, C.M.; Sowmya, A. Learning a compact vein discrimination model with ganerated samples. IEEE Trans. Inf. Forensics Secur. 2020, 15, 635–650. [Google Scholar] [CrossRef] [Scilit]
- Lu, Y.; Xie, S.J.; Wu, S.Q. Exploring competitive features using deep convolutional neural network for finger vein recognition. IEEE Access 2019, 7, 35113–35123. [Google Scholar] [CrossRef] [Scilit]
- Sabour, S.; Frosst, N.; Hinton, G.E. Dynamic routing between capsules. In Proceedings of the 31th Annual Conference on Neural Information Processing Systems (NIPS), Long Beach, CA, USA, 4–9 December 2017; pp. 3856–3866. [Google Scholar]
- Gumusbas, D.; Yildirim, T.; Kocakulak, M.; Acir, N. Capsule network for finger-vein-based biometric identification. In Proceedings of the IEEE Symposium Series on Computational Intelligence, Xiamen, China, 6–9 December 2019; pp. 437–441. [Google Scholar]
- Dosovitskiy, A.; Beyer, L.; Kolesnikov, A.; Weissenborn, D.; Zhai, X.; Unterthiner, T.; Houlsby, N. An image is worth 16 × 16 words: Transformers for image recognition at scale. In Proceedings of the International Conference on Learning Representations (ICLR), Virtual Event, 3–7 May 2021. [Google Scholar]
- Rice, J. Apparatus for the Identification of Individuals. US Patent No. 4,699,149, 19 March 1985. [Google Scholar]
- Kono, M.; Ueki, H.; Umemura, S. A new method for the identification of individuals by using of vein pattern matching of a finger. In Proceedings of the Fifth Symposium on Pattern Measurement, Yamaguchi, Japan, 20–22 January 2000; pp. 9–12. [Google Scholar]
- Miura, N.; Nagasaka, A.; Miyatake, T. Feature extraction of finger-vein patterns based on repeated line tracking and its application to personal identification. Mach. Vis. Appl. 2004, 15, 194–203. [Google Scholar] [CrossRef] [Scilit]
- Qin, H.F.; Qin, L.; Yu, C.B. Region growth-based feature extraction method for finger-vein recognition. Opt. Eng. 2011, 50, 214–229. [Google Scholar] [CrossRef] [Scilit]
- Miura, N.; Nagasaka, A.; Miyatake, T. Extraction of finger-vein patterns using maximum curvature points in image profiles. IEICE Trans. Inf. Syst. 2007, 90, 1185–1194. [Google Scholar] [CrossRef] [Scilit]
- Gupta, P.; Gupta, P. An accurate finger vein based verification system. Digit. Signal Process. 2015, 38, 43–52. [Google Scholar] [CrossRef] [Scilit]
- Rosdi, B.A.; Chai, W.S.; Suandi, S.A. Finger vein recognition using local line binary pattern. Sensors 2011, 11, 11357–11371. [Google Scholar] [CrossRef] [Scilit]
- Van, H.T.; Thai, T.T.; Le, T.H. Robust finger vein identification base on discriminant orientation feature. In Proceedings of the Seventh International Conference on Knowledge and Systems Engineering (KSE), Ho Chi Minh City, Vietnam, 8–10 October 2015; pp. 348–353. [Google Scholar]
- Hong, H.G.; Lee, M.B.; Park, K.R. Convolutional neural network-based finger-vein recognition using NIR image sensors. Sensors 2017, 17, 1297. [Google Scholar] [CrossRef] [Scilit]
- Zeng, J.; Wang, F.; Deng, J.; Qin, C.; Zhai, Y.; Gan, J.; Piuri, V. Finger vein verification algorithm based on fully convolutional neural network and conditional random field. IEEE Access 2020, 8, 65402–65419. [Google Scholar] [CrossRef] [Scilit]
- Wang, K.X.; Chen, G.H.; Chu, H.J. Finger vein recognition based on multi-receptive field bilinear convolutional neural network. IEEE Signal Process. Lett. 2021, 28, 1590–1594. [Google Scholar] [CrossRef] [Scilit]
- Li, Q.; Shen, L.; Guo, S.; Lai, Z. WaveCNet: Wavelet integrated CNNs to suppress aliasing effect for noise-robust image classification. IEEE Trans. Image Process. 2021, 30, 7074–7089. [Google Scholar] [CrossRef] [Scilit]
- Zou, Z.; Shi, Z.; Guo, Y.; Ye, J. Object detection in 20 years: A survey. CoRR 2019, abs/1905.05055. Available online: https://arxiv.org/abs/1905.05055 (accessed on 16 May 2019).
- Minaee, S.; Boykov, Y.Y.; Porikli, F.; Plaza, A.J.; Kehtarnavaz, N.; Terzopoulos, D. Image segmentation using deep learning: A survey. IEEE Trans. Pattern Anal. Mach. Intell. 2021, 44, 3523–3542. [Google Scholar] [CrossRef] [Scilit]
- Degardin, B.; Proença, H. Human behavior analysis: A survey on action recognition. Appl. Sci. 2021, 11, 8324. [Google Scholar] [CrossRef] [Scilit]
- Carion, N.; Massa, F.; Synnaeve, G.; Usunier, N.; Kirillov, A.; Zagoruyko, S. End-to-end object detection with transformers. In Proceedings of the European Conference on Computer Vision (ECCV), Glasgow, UK, 23–28 August 2020; pp. 213–229. [Google Scholar]
- Touvron, H.; Cord, M.; Douze, M.; Massa, F.; Sablayrolles, A.; Jégou, H. Training data-efficient image transformers & distillation through attention. In Proceedings of the 38th International Conference on Machine Learning (ICML), Virtual, 18–24 July 2021; pp. 10347–10357. [Google Scholar]
- Chen, B.; Li, P.; Li, C.; Li, B.; Bai, L.; Lin, C.; Ouyang, W. Glit: Neural architecture search for global and local image transformer. In Proceedings of the International Conference on Computer Vision (ICCV), Virtual Event. 11–17 October 2021; pp. 12–21. [Google Scholar]
- Lu, Y.; Xie, S.J.; Yoon, S.; Wang, Z.; Park, D.S. An available database for the research of finger vein recognition. In Proceedings of the IEEE International Congress on Image and Signal Processing (CISP), Dalian, China, 14–16 October 2014; pp. 410–415. [Google Scholar]
- Yin, Y.L.; Liu, L.L.; Sun, X.W. SDUMLA-HMT: A multimodal biometric database. In Proceedings of the Chinese Conference on Biometric Recognition (CCBR), Shanghai, China, 10–12 September 2011; pp. 260–268. [Google Scholar]
- FV-USM Finger vein Image Database (DB/OL). Available online: http://drfendi.com/fv_usm_datae (accessed on 22 January 2021).
- Lu, H.; Wang, Y.; Gao, R.; Zhao, C.; Li, Y. A novel ROI extraction method based on the characteristics of the original finger vein image. Sensors 2021, 21, 4402. [Google Scholar] [CrossRef] [Scilit]
- Qin, H.F.; Mounim, A. Deep representation for finger-vein image-quality assessment. IEEE Trans. Circuits Syst. Video Technol. 2018, 28, 1677–1693. [Google Scholar] [CrossRef] [Scilit]
- Kang, W.; Liu, H.; Luo, W.; Deng, F. Study of a full-view 3D finger vein verification technique. IEEE Trans. Inf. Forensics Secur. 2020, 15, 1175–1189. [Google Scholar] [CrossRef] [Scilit]
- Yao, Q.; Song, D.; Xu, X.; Zou, K. A novel finger vein recognition method based on aggregation of radon-like features. Sensors 2021, 21, 1885. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Tao, Z.; Wang, H.; Hu, Y.; Han, Y.; Lin, S.; Liu, Y. DGLFV: Deep generalized label algorithm for finger-vein recognition. IEEE Access 2021, 9, 78594–78606. [Google Scholar] [CrossRef] [Scilit]


| Database | Sampling Object | Image Resolution | Number of Classes | Number of Fingers | Total Images |
|---|---|---|---|---|---|
| MMCBNU | 100 | 320 240 | 600 | 6 | 6000 |
| SDUMLA | 106 | 320 240 | 636 | 6 | 3816 |
| FV-USM | 123 | 480 | 492 | 4 | 5904 |
| HKPU | 156 | 624 | 4 | 3132 |
| Database | Number of Layers | Heads | Routing Iterations | ACC (%) | EER (%) | AUC |
|---|---|---|---|---|---|---|
| MMCBNU | 1 | 12 | 3 | 96.54 | 0.66 | 1.0 |
| 24 | 97.52 | 0.63 | 1.0 | |||
| 2 | 12 | 4 | 95.29 | 1.12 | 1.0 | |
| 24 | 97.25 | 0.65 | 1 | |||
| SDUMLA | 1 | 12 | 3 | 91.98 | 2.15 | 0.99 |
| 24 | 94.97 | 1.13 | 1 | |||
| 2 | 12 | 4 | 92.45 | 2.38 | 0.99 | |
| 24 | 93.24 | 1.74 | 0.99 | |||
| FV-USM | 1 | 12 | 3 | 97.76 | 1.01 | 1.0 |
| 24 | 98.68 | 0.29 | 1.0 | |||
| 2 | 12 | 4 | 97.82 | 0.28 | 1.0 | |
| 24 | 97.92 | 0.60 | 1.0 | |||
| HKPU | 1 | 12 | 3 | 92.62 | 3.53 | 0.99 |
| 24 | 93.45 | 2.93 | 0.99 | |||
| 2 | 12 | 4 | 95.36 | 2.56 | 0.99 | |
| 24 | 95.61 | 1.66 | 0.99 |
| Database | Number of Layers | Heads | Routing Iterations | ACC (%) | EER (%) | AUC |
|---|---|---|---|---|---|---|
| MMCBNU | 12 | 24 | 6 | 96.08 | 0.72 | 1 |
| SDUMLA | 12 | 24 | 6 | 92.14 | 1.63 | 1 |
| FV-USM | 12 | 24 | 6 | 98.35 | 0.55 | 1 |
| HKPU | 12 | 24 | 6 | 95.48 | 1.71 | 0.99 |
| Model | ACC (%) |
|---|---|
| Resnet50 + CapsNet | 93.13 |
| MobilenetV3 + CapsNet | 89.07 |
| Proposed | 95.23 |
| Datasets | Training | Testing | Accuracy | ||||
|---|---|---|---|---|---|---|---|
| State-of-the-Art Methods | |||||||
| ViT | Capsule Net | CNN [9] | MC [19] | ViT-Cap | |||
| MMCBNU | 6 images | remaining 4 images | 95.13 | 96.29 | - | - | 97.52 |
| SDUMLA | 5 images | remaining 1 image | 90.88 | 95.66 | 97.48 | 97.95 | 93.24 |
| FV-USM | 8 images | remaining 4 images | 95.99 | 96.47 | 97.53 | 90.34 | 98.68 |
| HKPU | 8 images | remaining 4 images | 87.62 | 95.07 | 95.13 | 85.24 | 95.61 |
| Algorithm | Year | MMCBNU | SDUMLA | FV-USM | HKPU |
|---|---|---|---|---|---|
| Miura et al. [17] | 2003 | 5.74 | 5.85 | - | 3.32 |
| Miura et al. [19] | 2005 | 2.69 | 3.65 | - | 2.41 |
| Qin et al. [37] | 2018 | - | - | 0.80 | 2.33 |
| Kang et al. [38] | 2019 | 1.69 | 0.94 | 2.40 | |
| Yao et al. [39] | 2021 | 1.68 | - | 2.12 | 4.23 |
| Tao et al. [40] | 2021 | - | 2.23 | - | - |
| Proposed | 2021 | 0.63 | 1.3 | 0.28 | 1.66 |
| Datasets | Training | Testing | Model | ACC (%) | EER (%) | AUC |
|---|---|---|---|---|---|---|
| MMCBNU | 4 images | 1 image | Capsule | 90.83 | 1.87 | 0.99 |
| ViT-Cap | 91.66 | 1.17 | 0.99 | |||
| 3 images | 1 image | Capsule | 86.66 | 2.53 | 0.99 | |
| ViT-Cap | 87.16 | 2.49 | 0.99 | |||
| SDUMLA | 4 images | 1 image | Capsule | 88.50 | 5.06 | 0.98 |
| ViT-Cap | 90.25 | 3.11 | 0.99 | |||
| 3 images | 1 image | Capsule | 81.13 | 8.02 | 0.97 | |
| ViT-Cap | 82.71 | 4.13 | 0.99 | |||
| FV-USM | 4 images | 1 image | Capsule | 93.08 | 1.46 | 0.99 |
| ViT-Cap | 94.31 | 2.21 | 0.99 | |||
| 3 images | 1 image | Capsule | 88.33 | 4.52 | 0.99 | |
| ViT-Cap | 89.02 | 3.61 | 0.99 | |||
| HKPU | 4 images | 1 image | Capsule | 89.04 | 4.24 | 0.98 |
| ViT-Cap | 93.09 | 2.35 | 0.99 | |||
| 3 images | 1 image | Capsule | 82.38 | 8.94 | 0.96 | |
| ViT-Cap | 92.14 | 2.31 | 0.99 |
Publisher’s Note: MDPI stays neutral with regard to jurisdictional claims in published maps and institutional affiliations. |
© 2022 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).
Share and Cite
Li, Y.; Lu, H.; Wang, Y.; Gao, R.; Zhao, C. ViT-Cap: A Novel Vision Transformer-Based Capsule Network Model for Finger Vein Recognition. Appl. Sci. 2022, 12, 10364. https://doi.org/10.3390/app122010364
Li Y, Lu H, Wang Y, Gao R, Zhao C. ViT-Cap: A Novel Vision Transformer-Based Capsule Network Model for Finger Vein Recognition. Applied Sciences. 2022; 12(20):10364. https://doi.org/10.3390/app122010364
Chicago/Turabian StyleLi, Yupeng, Huimin Lu, Yifan Wang, Ruoran Gao, and Chengcheng Zhao. 2022. "ViT-Cap: A Novel Vision Transformer-Based Capsule Network Model for Finger Vein Recognition" Applied Sciences 12, no. 20: 10364. https://doi.org/10.3390/app122010364
APA StyleLi, Y., Lu, H., Wang, Y., Gao, R., & Zhao, C. (2022). ViT-Cap: A Novel Vision Transformer-Based Capsule Network Model for Finger Vein Recognition. Applied Sciences, 12(20), 10364. https://doi.org/10.3390/app122010364