


1. Error in Figure
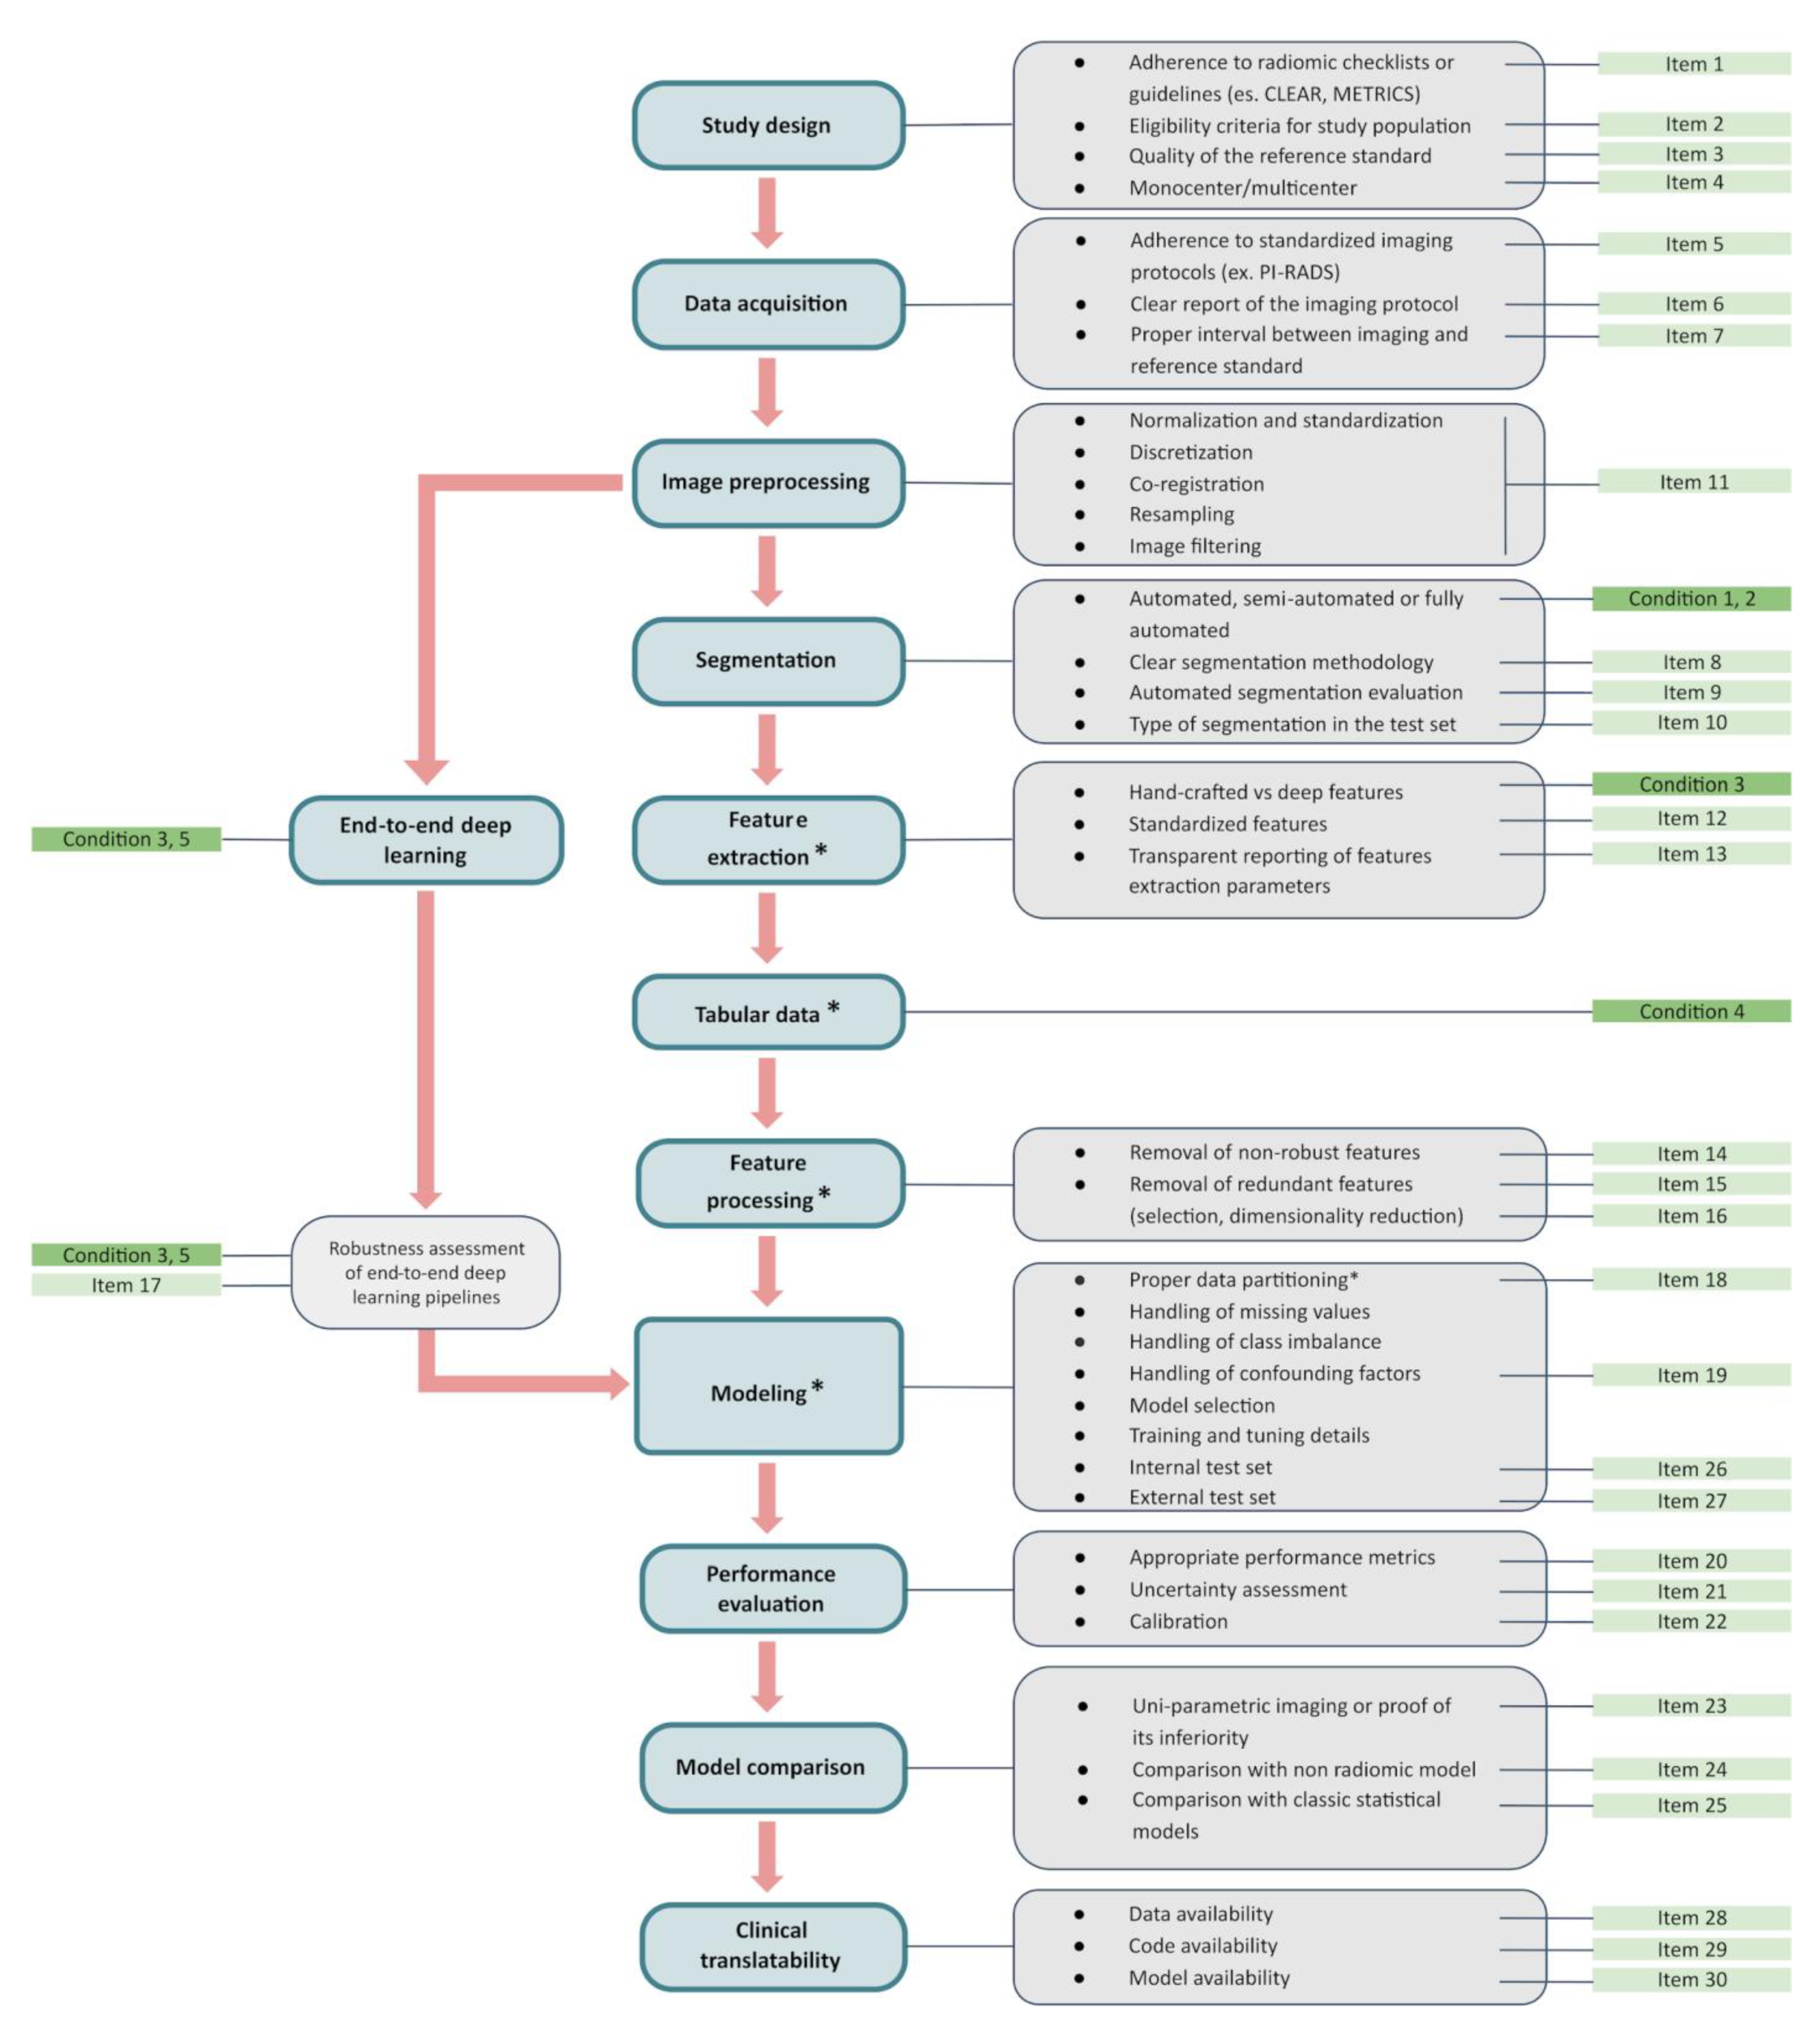
In the original publication [1], Figure 2 was inaccurate, as suggested by a reader on PubPeer. The tip of the arrow was therefore moved towards “modeling” and an asterisk was added to stress the concept that feature extraction and processing should be performed solely on the training set after data partitioning, as clearly stated in the text. The new version of Figure 2 and the figure legend appear below.
Figure 2.
The main steps, the specific sub-tasks for each phase, and the related METRICS items. * To avoid data leakage and overfitting, data partitioning should be performed before feature extraction, processing, and model training.
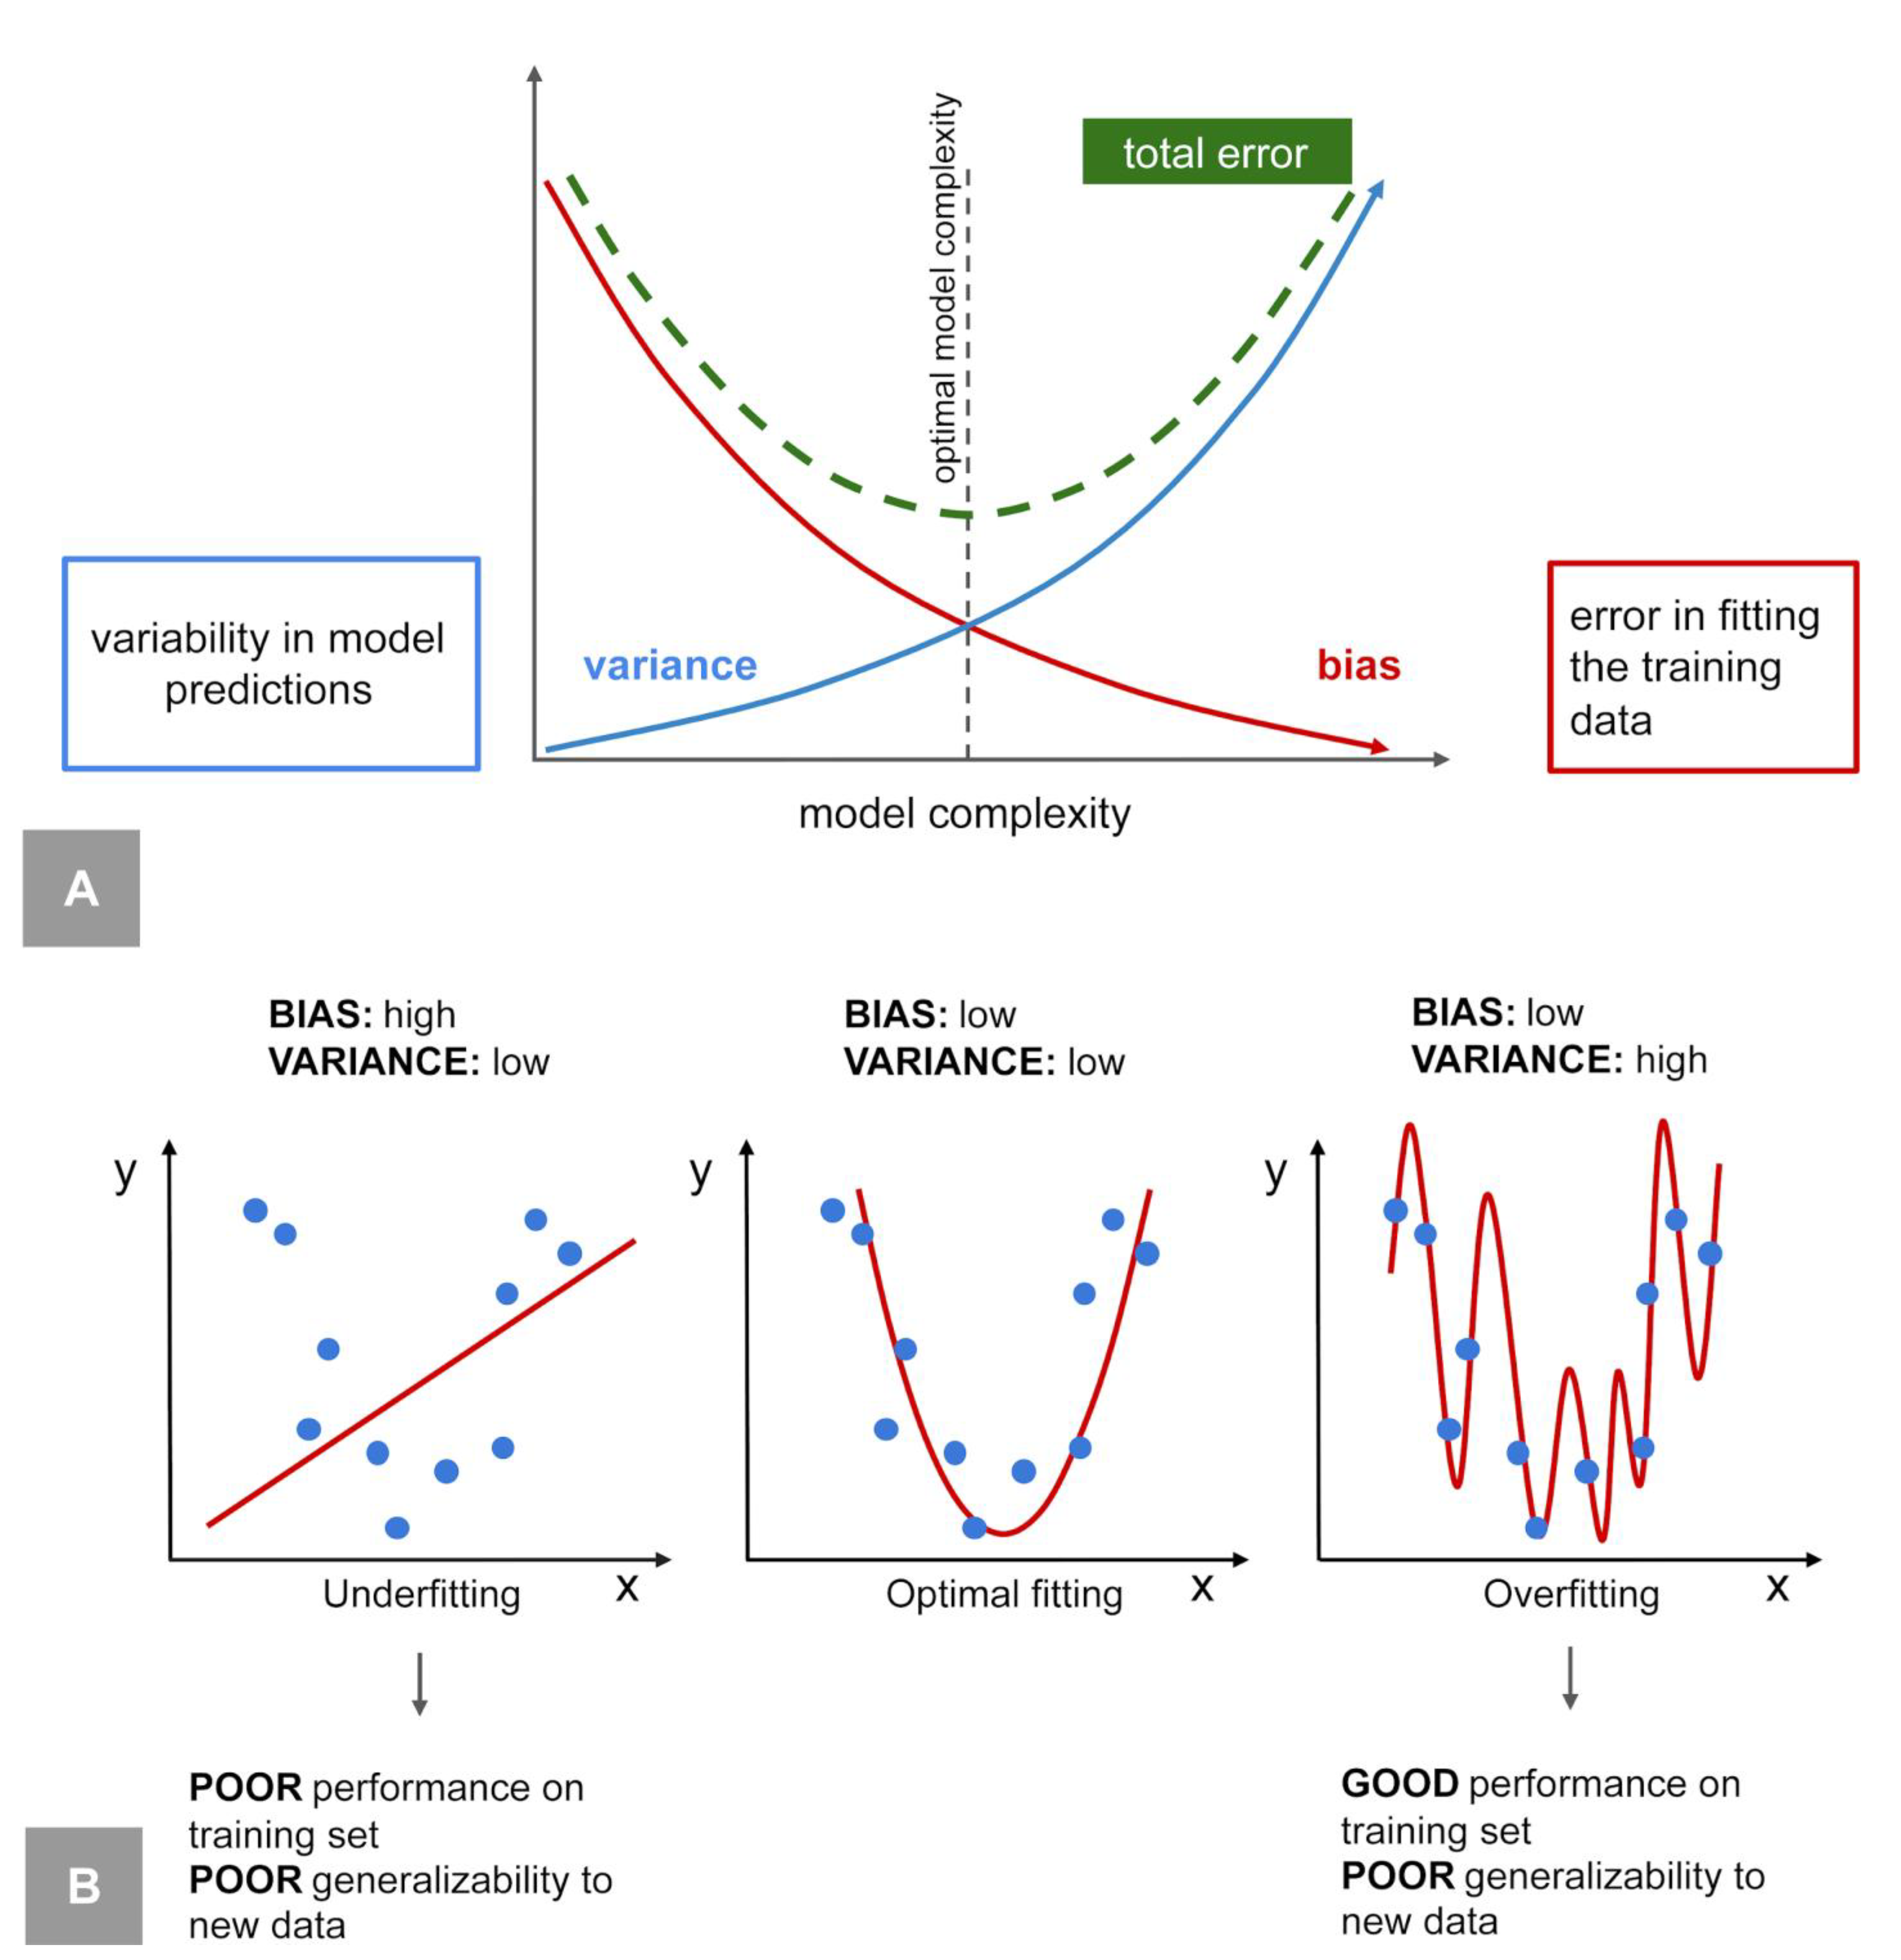
In the original publication [1], there was a typo in Figure 4: the word “high” was duplicated. The new version of Figure 4 and the figure legend appear below.
Figure 4.
Bias–variance trade-off, overfitting, and underfitting. (A) Bias–variance trade-off. As the complexity of the model increases, the bias decreases but the variance increases. More complex models can capture intricate patterns in the data, better fitting the training dataset and reducing systematic errors (bias), but they also become more sensitive to noise and specific data points, leading to higher variability in model predictions (variance). (B) Overfitting and underfitting. Overfitting occurs when a model captures noise and fluctuations in the training data rather than the underlying patterns, resulting in an excellent performance on the training set (low bias) but poor generalizability to new data (high variance). Underfitting happens when a model is too simple to detect the underlying patterns, leading to a poor performance on both the training (high bias) and testing datasets.
2. Text Correction
The second-to-last paragraph of Section 3 was amended as follows: “By introducing regularization and feature selection, the model’s variance reduces and the model’s performance on unseen data improves, at the cost of slightly increasing the model’s bias. Underfitting occurs when a model has high bias and low variance, resulting in a poor performance for both training and testing data. This often happens when the model is too simple or the training data are insufficient.”
The first sentence of Section 4.8.1 was updated as follows: “Not all extracted features are useful for modeling, hence the need for feature selection (METRICS item 15 [20]) [111], which must be performed solely on the training set.”
The authors state that the scientific conclusions are unaffected. This correction was approved by the Academic Editor. The original publication has also been updated.
Reference
- Cè, M.; Chiriac, M.D.; Cozzi, A.; Macrì, L.; Rabaiotti, F.L.; Irmici, G.; Fazzini, D.; Carrafiello, G.; Cellina, M. Decoding Radiomics: A Step-by-Step Guide to Machine Learning Workflow in Hand-Crafted and Deep Learning Radiomics Studies. Diagnostics 2024, 14, 2473. [Google Scholar] [CrossRef] [Scilit] [PubMed]
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.