


Abstract
Mobile edge computing (MEC) enables resource-constrained mobile devices to execute delay-sensitive and compute-intensive applications by offloading tasks to nearby edge servers. However, task orchestration in MEC is challenged by the highly dynamic system conditions, unreliable networks, and distributed edge environments. Moreover, as the number of mobile users, tasks, and distributed computing resources (edge/cloud servers) increases, the task orchestration process becomes more complex due to the expanded decision space and the need to efficiently allocate heterogeneous resources under latency and capacity constraints. As the decision space grows, exhaustive-search-based orchestration becomes computationally infeasible. Clustering approaches often rely on proximity-only grouping, while learning-based solutions require extensive training and parameter tuning. To address these challenges, this paper proposes a Multi-Criteria Hierarchical Clustering-based Task Orchestrator (MCHC-TO), a novel framework that integrates multi-criteria decision making with divisive hierarchical clustering for preference-aware and adaptive workload orchestration. Edge servers are first evaluated using multiple decision criteria, and the resulting preference rankings are exploited to form hierarchical preference-based clusters. Incoming tasks are then assigned to the most suitable cluster based on task requirements, enabling efficient resource utilization and dynamic decision-making. Extensive simulations conducted using an edge computing simulator demonstrate that the proposed MCHC-TO framework consistently outperforms benchmark approaches, achieving reductions in average service delay and task failure rate of up to 48% and 92%, respectively. These results highlight the effectiveness of combining multi-criteria evaluation with hierarchical clustering for robust and dynamic task orchestration in MEC environments.
1. Introduction
Edge Computing (MEC) is an emerging paradigm that brings processing and storage capabilities closer to end-users at the network edge, enabling real-time, low-latency, and scalable services. A key enabler of MEC is computation offloading, whereby tasks are transferred from resource-constrained devices, such as smartphones, to more powerful edge servers. This can reduce response time, conserve device energy, and alleviate core network congestion [1]. However, effective offloading is a complex, multi-level decision-making process that involves selecting which tasks to offload, determining where and when to execute them, allocating computing resources, and selecting efficient network paths [2]. Within this process, task orchestration plays a central role in coordinating offloading decisions and ensuring efficient task placement across distributed layers.
Task orchestration in MEC faces several challenges, including highly dynamic workload patterns, system stochasticity, and resource heterogeneity. Moreover, as the scale of mobile users, application tasks, and distributed computing nodes increases, task orchestration becomes more challenging due to the rapid expansion of the decision space and resource constraints. Moreover, as the number of mobile users, application tasks, and candidate execution nodes increases, task orchestration becomes more challenging due to the rapid expansion of the decision space and the need to satisfy latency, network, and resource constraints. To mitigate this complexity, several approaches have been explored, including optimisation-based methods, heuristic scheduling strategies, and learning-based techniques. However, these approaches may incur high computational overhead or require extensive training in dynamic environments. Clustering can be integrated into MEC to reduce the search space for real-time decision making [3]. By forming effective clusters of edge servers, an orchestrator can avoid system-wide searches during task placement, enabling faster decisions and improved efficiency. However, achieving such clustering requires balancing multiple, often conflicting criteria, such as user mobility, server CPU utilization, network conditions, and task characteristics (e.g., computational demand and delay sensitivity). Traditional clustering algorithms are not well suited to this setting because they typically form homogeneous clusters based on distance-like similarity measures only. In other words, these methods quantify similarity between objects without explicitly modeling preference or priority relationships [4], which limits their effectiveness for dynamic task orchestration.
Although clustering has been investigated in several MEC studies, most existing works rely on classical techniques and focus on clustering tasks [5,6,7], end devices [3,8,9,10], network sensors [11], or base stations [12]. Only a limited number of studies, such as [13], consider clustering edge servers, despite their central role in MEC orchestration. In [13], edge nodes are clustered using an energy-transfer distance metric to improve energy efficiency; however, the clustering relies on a single distance criterion and does not explicitly capture the trade-offs among multiple decision factors relevant to orchestration decisions. To address the limitations of classical clustering in this context, this study leverages multi-criteria decision-making (MCDM) methods [14] to develop a relational clustering approach. This approach is built on a multi-criteria framework and incorporates the decision-maker’s preferences, thus supporting complex decision-making processes.
Accordingly, this paper proposes the Multi-Criteria Hierarchical Clustering-based Task Orchestrator (MCHC-TO), a framework that dynamically allocates tasks to the most suitable servers using divisive hierarchical clustering guided by multi-criteria evaluations. The central hypothesis tested in this work is that integrating multi-criteria preference evaluation with hierarchical server clustering can (i) reduce service delay and task failures and (ii) improve load balancing compared with classical clustering and representative orchestration baselines under diverse workload conditions. Extensive simulation results support this hypothesis and show that MCHC-TO consistently improves key performance metrics.
This work introduces a new perspective by formulating MEC task orchestration as a multi-criteria relational clustering problem. The main contributions of are as follows:
- The MEC task orchestration problem is formulated as a dynamic divisive hierarchical clustering problem guided by multi-criteria evaluations, where relational grouping of edge servers captures trade-offs among multiple criteria (e.g., server capacity and proximity) under varying system loads.
- Based on this formulation, a preference-aware hierarchical clustering framework for MEC is proposed to reduce average service delay and task failure rate while maintaining balanced utilization of edge resources.
- The effectiveness of MCHC-TO is demonstrated through extensive simulations and comparisons with orchestration methods from the literature, as well as a specifically developed single-criterion clustering baseline. The results indicate that MCHC-TO reduces service delay, decreases task failure rates, and improves load distribution across edge resources.
- The remainder of this paper is organized as follows: Section 2 reviews task orchestration in MEC, with a focus on clustering-based solutions. Section 3 presents MCHC-TO, including its architecture and operational phases. Section 4 reports the performance evaluation, and Section 5 concludes the paper.
2. Related Work
Recent research has extensively investigated task orchestration, offloading, and resource allocation in MEC. This study focuses on decision-making approaches that explicitly determine the execution location of tasks across available computing layers. In the literature, this execution-location decision is described using different terms. Some studies refer to it as task orchestration [15,16,17,18], while others describe it as task offloading or resource allocation [19,20]. Additionally, several works formulate the problem as a scheduling or task assignment [13,21,22]. These terminological differences are reflected in Table 1, which compares existing approaches based on their decision scope, execution location, and algorithmic methodology.
Early approaches to MEC orchestration relied on rule-based techniques. Sonmez et al. [15] proposed a two-stage fuzzy logic-based orchestrator that considered task requirements, edge server capabilities, and network conditions to define a set of fuzzy rules used to select the execution location. Similarly, Jamil et al. [16] introduced a two-stage Belief Rule-Based (BRB) orchestrator that distinguished between delay-sensitive and delay-tolerant applications using conjunctive and disjunctive belief rules. Their approach achieved higher success rates than the fuzzy-based method by better capturing application requirements and execution environments. While rule-based approaches can be effective, they require manual rule design and tuning, which becomes increasingly complex and less scalable as MEC systems grow and evolve [21].
To overcome these limitations, many recent studies have adopted machine learning (ML) and reinforcement learning (RL) techniques to automate orchestration decisions. For instance, the authors of [17] proposed a two-stage model combining a multilayer perceptron (MLP)-based classification and regression to predict offloading success and service time in vehicular edge computing, achieving improved Quality of Experience (QoE). Yamansavascilar et al. [18] introduced DeepEdge, a Double Deep Q-Network (DDQN)-based orchestrator designed to select execution locations across edge and cloud servers in order to reduce task failure rates and improve edge resource utilization. In addition, Alfakih et al. [19] addressed offloading problem using a state–action–reward–state–action (SARSA)-based RL algorithm to minimize energy consumption and processing delay, outperforming Q-learning in their experiments. Similarly, Zheng et al. [21] developed a Deep Q-Network (DQN)-based orchestration framework that selects execution locations among local edge servers, multiple nearby edge servers, and the cloud. Their approach outperformed Proximal Policy Optimization (PPO) and Deep Deterministic Policy Gradient (DDPG) models in terms of latency, resource utilization, and task success rate. More recently, Wu et al. [20] proposed a Deep Reinforcement Learning (DRL)-based online scheduler in an Internet of Things (IoT)–MEC–cloud framework that jointly considered performance and security trade-offs, achieving lower latency than offline baselines. Hsieh et al. [22] investigated task assignment in cooperative MEC systems using Markov decision process (MDP) and DRL models. Specifically, they developed and compared value-based Double Deep Q-Network (DDQN), policy-based Policy Gradient (PG), and hybrid Actor–Critic (AC) approaches to optimize execution delay and energy consumption under dynamic conditions. Similarly, Liu et al. [23] proposed a Multi-agent reinforcement learning (MARL) framework in which edge nodes collaboratively learn resource allocation and scheduling policies through decentralized DQN-based training.
Although learning-driven approaches can adapt to changing network conditions and often achieve significant performance gains, they typically require extensive training, careful parameter tuning, and considerable computational overhead. These requirements can limit their practicality in large-scale or resource-constrained MEC environments. As a result, alternative solutions that reduce computational complexity while maintaining adaptability remain of interest.
Clustering-based methods offer a training-free and interpretable alternative by reducing the search space for orchestration decisions. Shooshtarian et al. [24] proposed a two-stage hierarchical clustering approach for resource allocation in fog computing, in which fog nodes were grouped based on resource characteristics and tasks were assigned to the nearest fog layer to minimize latency. However, the proximity-based layer selection strategy may have overlooked better resource options in other layers, limiting its adaptability. Hao et al. [13] introduced an energy-aware clustering approach in MEC, where edge nodes were clustered using attenuation-based distance metrics and a heuristic scheduler managed intra- and inter-cluster allocations. Since clustering was performed only once during system initialization, the approach was not well-suited to dynamic workloads. Moreover, classical distance-based clustering methods often suffer from scalability and dimensionality challenges as system complexity increases [25].
To address these limitations, some studies have integrated clustering with MCDM. De Smet et al. [26] extended K-means to a preference-based clustering approach, in which binary relations were used to define similarity instead of conventional distance measures. Subsequent works proposed divisive hierarchical clustering approaches based on the Preference Ranking Organization Method for Enrichment Evaluation (PROMETHEE), which provides preference-based rankings to guide cluster formation [27]. Later studies further extended this approach by incorporating uncertainty modeling techniques, such as Stochastic Multiobjective Acceptability Analysis (SMAA), to explicitly handle uncertainty in preference modeling [4]. While these methods offer flexible, preference-driven clustering, their applications have largely been limited to financial and decision analysis domains, rather than MEC or task orchestration.
In recent MEC orchestration literature, many server clustering and load balancing mechanisms group edge servers using distance-based or single-metric criteria (e.g., geographical proximity, residual capacity, or load level), often relying on static K-means/K-medoids partitioning. While such approaches are computationally efficient, they typically optimize a limited aspect of the system state. In parallel, learning-based solutions employ DRL or predictive models to learn task assignment policies from historical interactions, introducing training complexity and convergence considerations. In contrast, the proposed MCHC-TO framework adopts a preference-driven multi-criteria orchestration strategy. Instead of relying on a single metric or purely data-driven policy learning, edge servers are evaluated using a structured multi-criteria decision-making mechanism that captures multiple performance aspects simultaneously. The resulting preference relationships guide a hierarchical clustering process, enabling adaptive task offloading decisions that are both multi-dimensional and dynamically updated without requiring iterative model training. This integrated multi-criteria and preference-guided design differentiates MCHC-TO from existing MEC clustering and load balancing approaches. A comparative overview of representative methods is provided in Table 1, highlighting the methodological distinctions and gaps addressed by the proposed framework.
Table 1.
Comparison of this study’s work with existing related works.
3. Multi-Criteria Hierarchical Cluster-Based Task Orchestration
The goal of this paper is to enhance task execution efficiency in MEC environments by intelligently selecting the most suitable servers. To achieve this, we integrate MCDM with a hierarchical clustering strategy, enabling the formation of high-ranking clusters of edge servers for task execution at the edge layer. This section presents the proposed Multi-Criteria Hierarchical Clustering-based Task Orchestrator (MCHC-TO) framework. First, the system architecture and key assumptions are described. Then, the multi-criteria evaluation process, preference-driven hierarchical clustering, and task allocation mechanism are detailed. Table 2 summarizes the main symbols and notations used throughout this section.
Table 2.
Notation and Symbols Used in the Proposed MCHC-TO Framework.
3.1. System Architecture
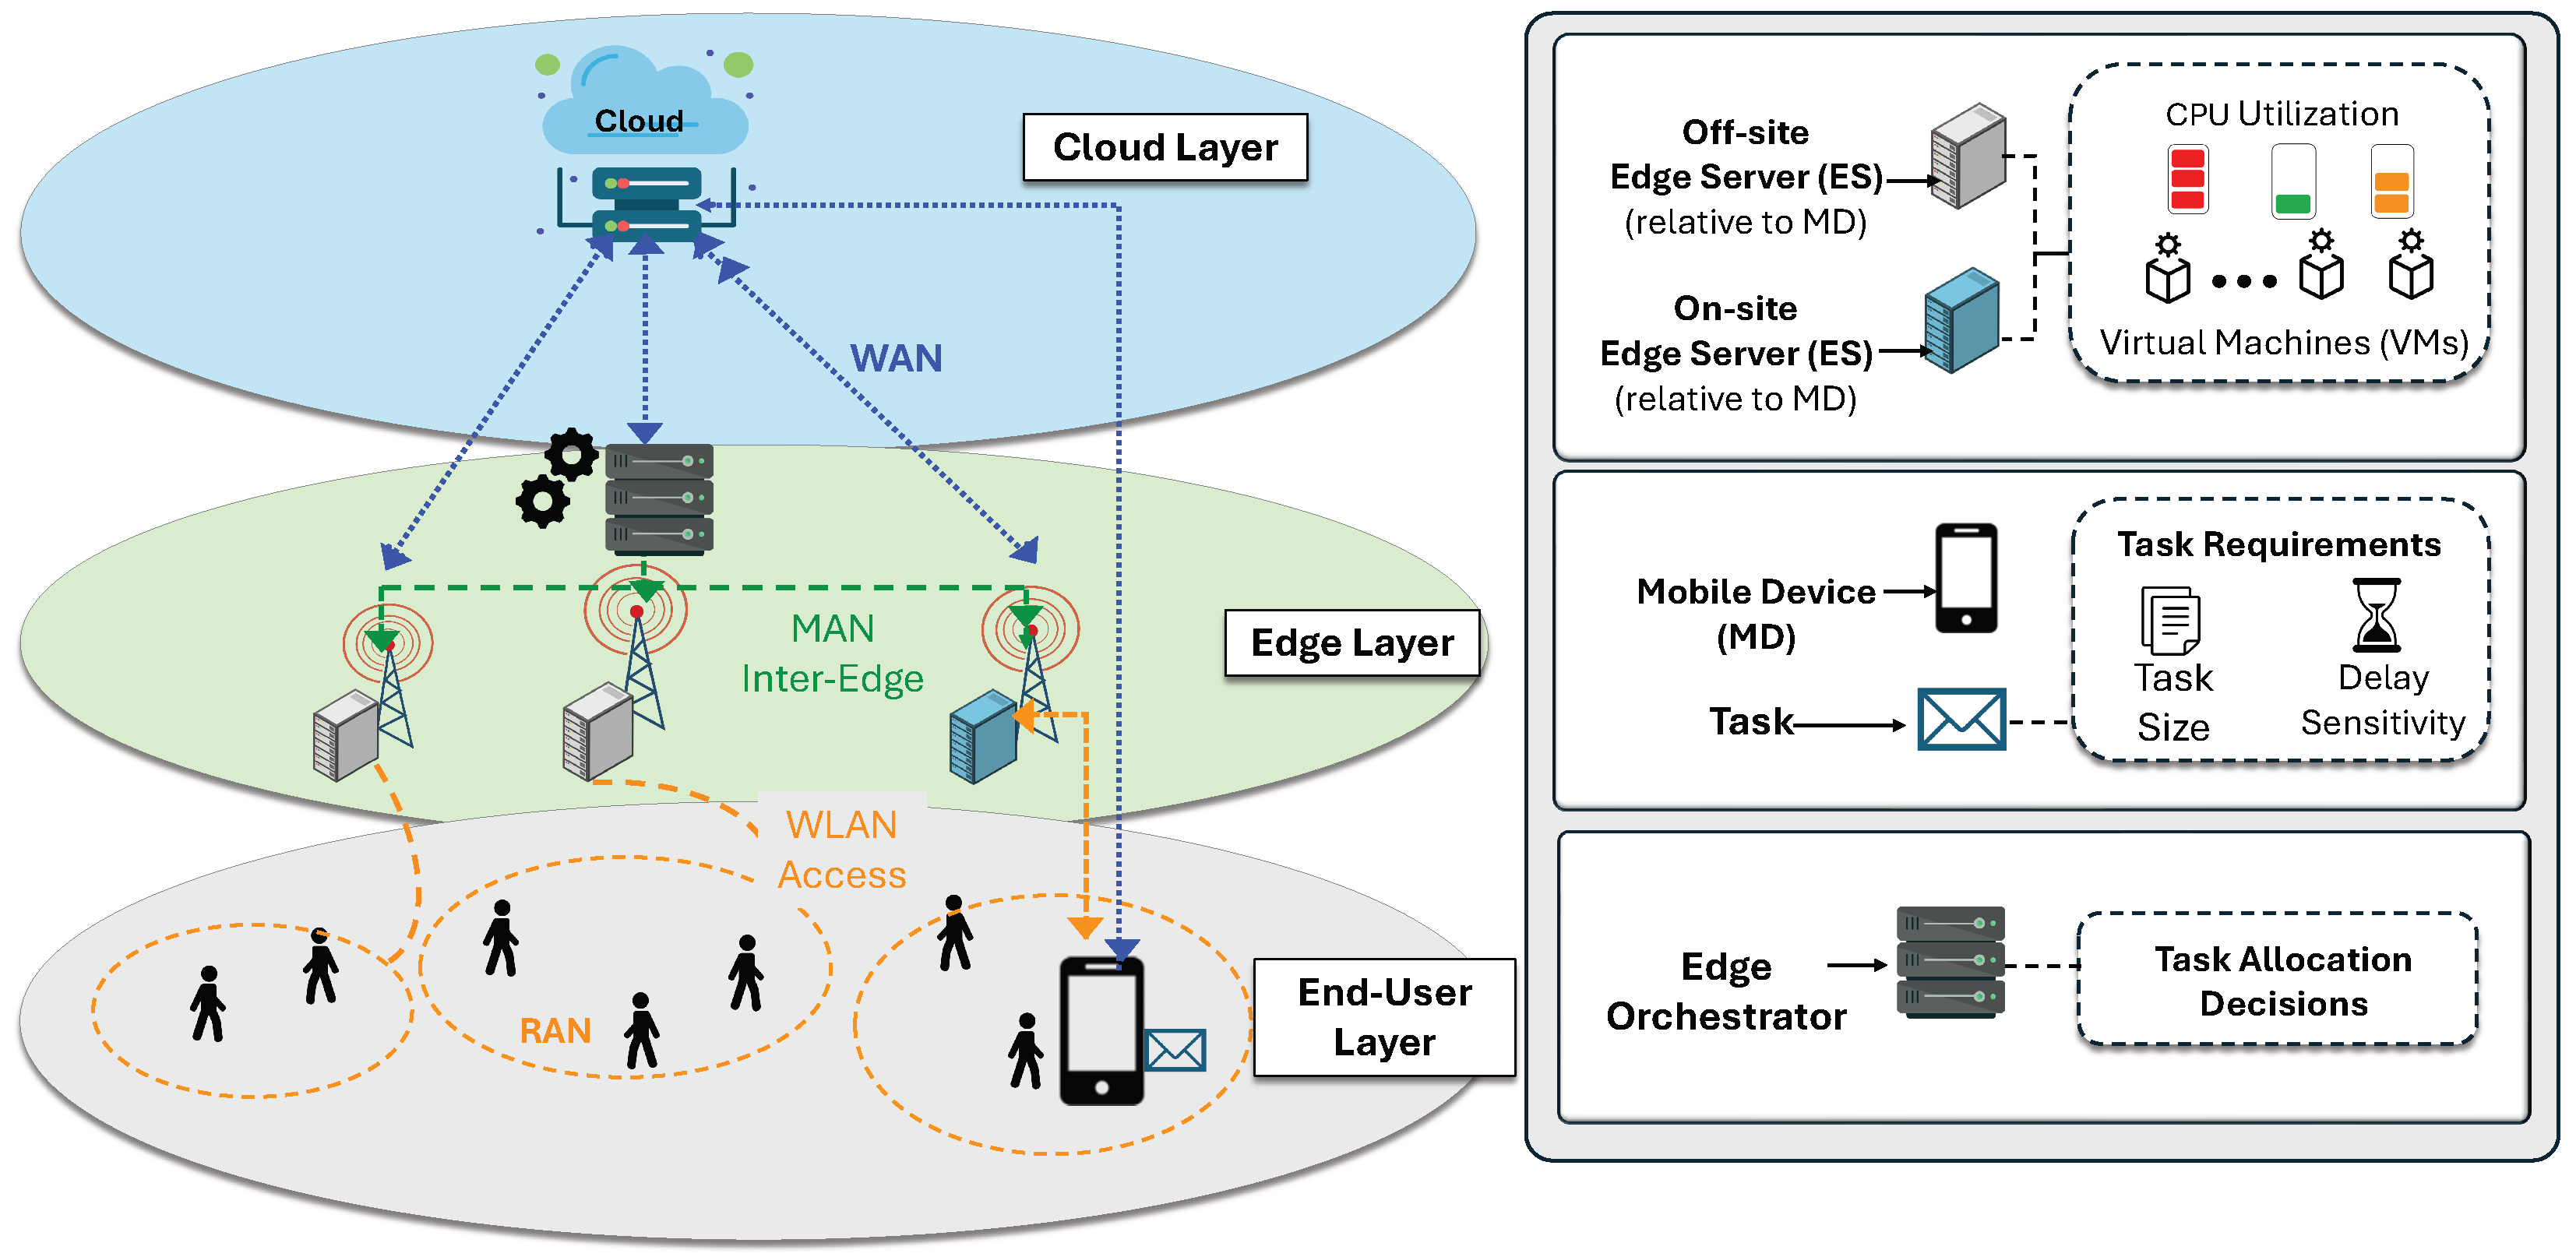
A three-tier MEC architecture, comprising end-user, edge, and cloud layers, is utilized to support the deployment of edge computing solutions, as illustrated in Figure 1. The system is heterogeneous in terms of different computing resource capabilities and different network ranges, such as wireless local area networks (WLAN), metropolitan area networks (MAN), and wide area networks (WAN). The model consists of several components organized into three layers, as follows:
Figure 1.
High-level overview of a multi-tier MEC architecture.
3.1.1. End-Users Layer
A layer in which users generate several tasks using their mobile devices (MDs), such as smartphones, tablets, sensors, and IoT devices, during their movement between different Radio Access Networks (RANs). The MD generates tasks from several applications that vary in terms of complexity and requirements. A task can be characterized by two parameters: , where denotes the task size, expressed as the number of instructions (in Million Instructions, MI). This parameter determines the execution time of the task on an edge or cloud server, depending on the processing capability of its Virtual Machines (VMs), which is typically measured in Million or Giga Instructions Per Second (MIPS/GIPS). denotes the delay sensitivity, which reflects how sensitive the task is to the increased latency caused by the network conditions or server utilization. The tasks are assumed to arrive independently at the servers, and each task must be executed at a single location.
3.1.2. Edge Layer
A layer comprises edge servers (ESs), denoted by , each of which is connected to a base station (BS) to share power. The MDs within the range of a BS can access the associated ESs via WLAN. The BS and ES are linked through high-speed connections such as fibre optics, making the transmission delay negligible [28]. Each ES hosts multiple CPU cores and VMs to support concurrent task execution. Tasks are accepted for execution only if a suitable VM is available on the selected ES. If no VM is available due to capacity constraints, the task cannot be run at that ES and is considered failed. The proximity of an ES to an MD influences communication latency. ESs may therefore be classified as on-site or off-site. As illustrated in Figure 1, the on-site ES (shown in blue) resides within the same Radio Access Network (RAN) as the MD, whereas off-site ESs (shown in gray) belong to neighboring RANs. Offloading to an off-site ES requires routing through the WLAN and the MAN; however, MAN latency is not affected by the physical distance between servers [15].
Server capacity is represented by the proportion of available VMs at each ES, consistent with the underlying MEC simulator where task execution feasibility is determined by VM availability. Low VM availability indicates higher resource contention and increased risk of task rejection or delay. Although additional factors such as queue length, VM heterogeneity, resource fragmentation, or instantaneous CPU utilization may further characterize server load, VM availability provides a direct and decision-relevant indicator at the orchestration level. Incorporating multiple low-level resource metrics would increase model complexity without proportionate benefit within the adopted VM-based execution framework.
In this study, the Edge Orchestrator (ER) deployed within the edge layer and interconnected with all ESs via a MAN, serves as the centralized decision entity within a bounded MEC control domain. It continuously monitors resource availability and determines the optimal offloading destination according to the adopted orchestration policy. The considered MEC architecture operates under bounded control domains, where each orchestrator manages a limited set of edge servers within a specific geographic area. For wider regions, multiple orchestrators operate in parallel, each responsible for its local domain. Such a distributed orchestration structure is consistent with SDN-inspired MEC control architectures reported in the literature [18]. Within a single bounded domain, the number of managed ESs remains limited, which constrains the control-plane overhead associated with centralized orchestration. Investigating collaborative or decentralized coordination among multiple ERs represents an interesting direction for future work.
3.1.3. Cloud Layer
The cloud layer consists of servers with high processing capabilities and large storage capacity, accessible via WAN. It can assist the edge layer by executing tasks, particularly delay-tolerant tasks, to enhance the overall system performance. Unlike ESs the cloud layer is assumed to provide sufficient computational capacity for admitted tasks; therefore, cloud-related failures are attributed to network transmission constraints rather than processing limitations.
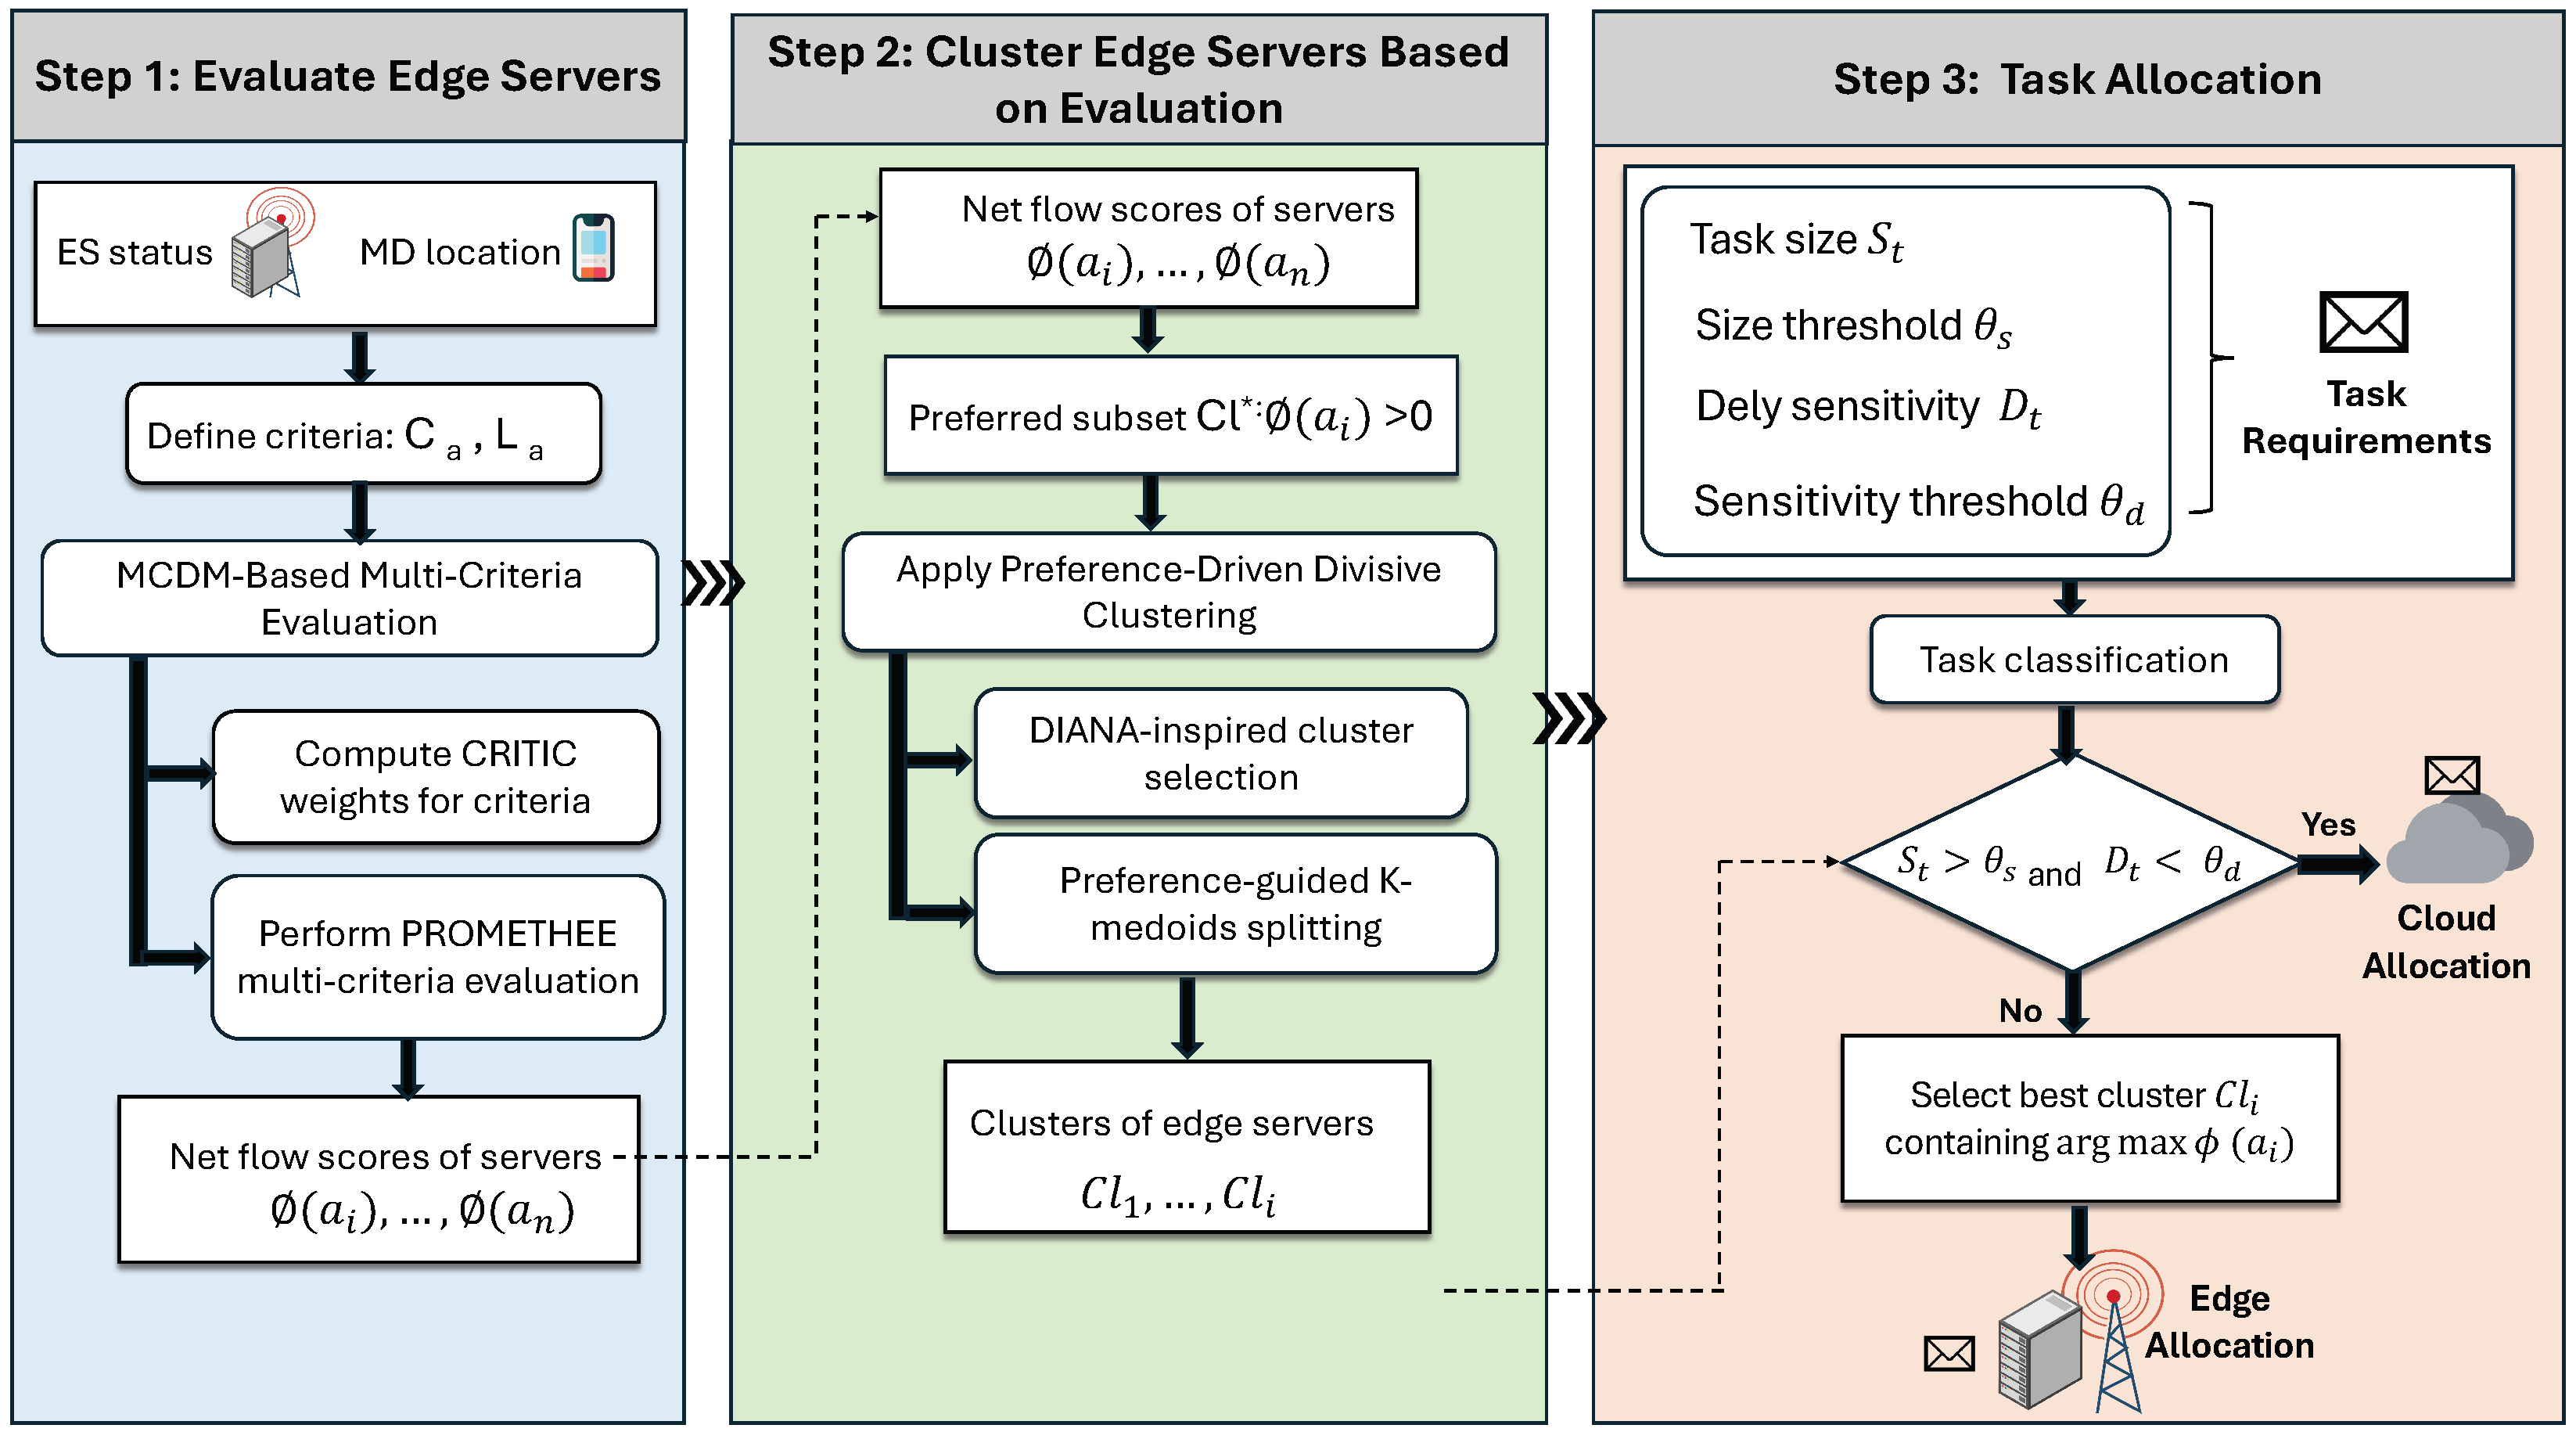
The proposed solution is structured into three main stages, which are detailed in the subsequent subsections and illustrated in Figure 2.
Figure 2.
Overview of the proposed MCHC-TO methodology, illustrating CRITIC-weighted PROMETHEE evaluation, preference-driven divisive hierarchical clustering, and task allocation.
3.2. MCDM-Based Multi-Criteria Evaluation
The first stage of the proposed MCHC-TO framework evaluated ESs based on multiple criteria, in order to identify the most suitable candidates for task offloading. One widely used family of MCDM methods is the Preference Ranking and Organization Method for Enrichment Evaluation (PROMETHEE), which facilitates systematic and transparent decision-making by ranking alternatives, such as ESs, based on multiple and sometimes conflicting criteria [29]. With PROMETHEE, preference functions and pairwise comparisons are utilized to generate a net flow score for each alternative, enabling decision-makers to identify the most suitable option based on their preferences and priorities.
This section presents the aspects of PROMETHEE that are relevant to the proposed algorithm and describes how they are incorporated into MEC to achieve targeted objectives. For a detailed exploration of the PROMETHEE family of methods and their applications, interested readers are referred to [30]. Algorithm 1 summarises the PROMETHEE-based multi-criteria evaluation step of the proposed framework and is illustrated in the blue box of Figure 2. The evaluation is performed through the following sequential stages.
3.2.1. Evaluation Criteria
The first step in PROMETHEE is to define the evaluation criteria, their associated weights, and preference thresholds, as these directly influence the final offloading decision. Consider the following multi-criteria problem:
where denotes the set of evaluation criteria, and A represents the set of ESs considered as alternatives. The selection of evaluation criteria in MCHC-TO is guided by the primary optimization objective, which is minimizing task service time. In the proposed system, service time is mainly composed of transmission delay and processing delay. Transmission delay is directly determined by the network type through which the task is offloaded (WLAN or MAN), which in turn is dictated by the location of the selected server. Processing delay, on the other hand, depends on the available computational capacity of the server, represented by its CPU resources and current VM load. Accordingly, the proposed solution considers two dominant criteria in ES evaluation as follows:
- : the server capacity, defined as the proportion of available virtual machines;
- : the server location, representing the proximity of the ES to the mobile device.
- These criteria directly influence the two fundamental components of service time and therefore capture the primary performance drivers relevant to the considered optimization goal. Although additional factors such as queue length, bandwidth variability and energy consumption may influence orchestration decisions in real MEC deployments, location and available capacity were selected because they directly determine transmission and processing delays. Queueing and bandwidth congestion effects are indirectly reflected through network delay modelling and VM capacity constraints. Moreover, the proposed framework is extensible and can incorporate additional criteria without modifying the underlying ranking and clustering structure.
3.2.2. Criteria Weighting Using CRITIC
Each criterion is assigned a weight , representing its relative importance, subject to the constraint:
PROMETHEE does not provide an inherent mechanism for determining criterion weights, which poses a challenge for objective decision-making [31]. To address this issue, the CRITIC (Criteria Importance Through Intercriteria Correlation) method is adopted to derive objective, data-driven criterion weights [32]. CRITIC evaluates the importance of each criterion based on its informational content, which is quantified through two components: (i) contrast intensity, measured by the standard deviation of criterion values, and (ii) inter-criteria conflict, captured through correlation coefficients.
For each criterion , let denote its standard deviation computed over all alternatives, and let denote the Pearson correlation coefficient between criteria and . Following the CRITIC method, the informational importance of criterion j is defined as [33]
and the corresponding objective weight is defined as
The CRITIC equations are applied to the decision matrix, in which alternatives A are represented by rows and criteria values , are represented by columns. This process ensures that the resulting weights reflect both the variability and redundancy of the criteria across all ESs. This step corresponds to the CRITIC-based weight computation stage in Algorithm 1, (lines 1–9).
| Algorithm 1 Multi-Criteria Evaluation using CRITIC-PROMETHEE |
| Input: Set of edge servers A, evaluation criteria , decision matrix , preference thresholds , . Output: Net flow scores . |
|
3.2.3. Preference Functions
In PROMETHEE, the comparison between alternatives is performed by transforming the difference in their evaluations under each criterion into a preference degree. For a given pair of alternatives and , the deviation with respect to criterion j is defined as
This deviation is then mapped to a preference degree using a preference function :
where represents the degree to which alternative is preferred over with respect to criterion j. The computation of criterion-level preference degrees corresponds to the preference evaluation stage in Algorithm 1, (lines 10–15). As defined in (1), both criteria are to be maximized; therefore, a positive deviation results in a non-zero preference degree.
In this paper, a widely adopted piecewise linear preference function is employed [31]:
where is the indifference threshold, representing the maximum deviation considered negligible, indicating that two alternatives are nearly equivalent within this range. Conversely, is the preference threshold, defining the minimum deviation required to establish a clear preference for one alternative over another. In the experimental evaluation, strict preference thresholds were adopted by setting , such that any non-zero deviation between alternatives results in a strict preference.
3.2.4. Pairwise Comparisons
Using the preference degrees obtained for each criterion, the overall preference of alternative over is computed by aggregating criterion-level preferences across all criteria:
This aggregation yields the global preference index and corresponds to the pairwise preference computation in Algorithm 1, (lines 11–18).
3.2.5. Net Flow Computation
To evaluate each alternative with respect to all other alternatives, PROMETHEE computes two preference flow scores. The positive (outgoing) flow reflects how much an alternative is preferred over the others:
while the negative (incoming) flow captures how much the alternative is outranked by the others:
The net flow score, which provides a unique overall preference value for each alternative, is then obtained as
where . This process yields a set of net flow scores for all ESs:
The resulting net flow scores quantify the overall dominance of each ES relative to the others and are subsequently used to guide the hierarchical clustering process for task orchestration decisions. The computation of positive, negative, and net preference flows corresponds to the net flow evaluation stage in Algorithm 1, (lines 19–24).
In the next stage, a preference-driven clustering algorithm groups ESs based on their net flow values, enabling scalable and adaptive task assignment, as detailed in Algorithm 2.
| Algorithm 2 Preference-Driven Divisive Hierarchical Clustering | |
| Input: Net flow scores from Algorithm 1 | |
| Output: Hierarchical clusters and the final selected singleton cluster | |
| |
| |
| ▹ preferred cluster |
| ▹ complementary cluster |
| |
| |
| |
| ▹ select non-singleton cluster containing highest net flow |
| |
| ▹ best net flow medoid |
| ▹ worst net flow medoid |
| |
| |
| |
| |
| |
| |
| |
| |
| |
| |
| |
| |
| |
| |
| |
| |
3.3. Preference-Driven Divisive Hierarchical Clustering
In MCHC-TO, a customized divisive hierarchical clustering technique is adopted to address the multi-criteria nature of task orchestration in MEC. This stage is illustrated in the green box of Figure 2. The proposed clustering strategy combines DIvisive ANAlysis (DIANA)-inspired divisive cluster selection with a preference-guided K-medoids splitting mechanism, both of which are detailed in the following subsubsections.
The process starts by placing all ESs into a single root cluster and iteratively splits clusters into smaller, preference-informed groups to identify the most suitable servers for task execution. At each iteration, the clustering process is guided by the PROMETHEE-derived net flow scores . Initially, ESs with positive net flow values () are assigned to a target cluster , while ESs with negative net flow values form its complementary cluster , as described in Algorithm 2 (lines 2–5). PROMETHEE theory establishes that alternatives with positive net flow values exhibit a higher global preference than those with negative net flows. As established in prior PROMETHEE-based work [27], this property enables the identification of a subset that maximizes the preference difference between the subset and its complement. Accordingly, assigning ESs with to ensures the selection of a preferred subset of servers with respect to the global preference relation.
Formally, the preferred subset is defined by
where is the complement of the cluster within the set A. As a result, the cluster dominates its complement in terms of aggregated preference, effectively reducing the solution space by excluding less competitive ESs from further consideration. A net flow value close to zero indicates weak dominance and reflects alternatives with comparable performance across the evaluation criteria. Additionally, when most ESs exhibit similar net flow values, the initial split serves as a preliminary grouping rather than a strict separation. The subsequent hierarchical refinement stage further differentiates alternatives based on preference differences, ensuring stable clustering and meaningful server selection even when performance scores are closely similar.
3.3.1. Cluster Selection and Termination
Following DIANA’s greedy divisive strategy [34], only one cluster is selected for further division at each iteration. In the proposed method, this cluster is chosen as the non-singleton cluster containing the ES with the highest net flow value (Algorithm 2, line 8). This strategy ensures that computation focuses on the most promising subset while reducing unnecessary processing of less competitive groups. The process continues until all clusters become singletons, yielding a preference-refined hierarchical structure for task allocation.
For each orchestration decision, the PROMETHEE preference matrix and the corresponding net flow scores are computed using the current system state. Once the net flow values are obtained for that decision step, the subsequent hierarchical splitting operates on these fixed preference scores, producing a deterministic cluster structure for the evaluated server set. As system conditions evolve (e.g., changes in VM availability or network delays), the preference matrix and the corresponding net flow values are recomputed for the next orchestration decision, allowing the method to adapt dynamically to changing MEC conditions.
3.3.2. Preference-Guided Cluster Splitting
Once the preferred cluster is identified, MCHC-TO applies a modified K-medoids splitting procedure to partition the cluster into two sub-clusters. The medoids are selected deterministically as the ESs with the highest and lowest net flow values within the cluster, ensuring maximal preference divergence between the resulting sub-clusters (Algorithm 2, lines 10–11). Each ES is then assigned to the closest medoid based on the absolute difference in net flow values, , which serves as a preference-based similarity measure (Algorithm 2, lines 14–20).
Unlike classical DIANA, which relies on full pairwise dissimilarity matrices and repeated distance updates, the proposed approach computes similarity only with respect to the two extreme medoids at each level. This reduces the number of required distance evaluations from pairwise comparisons to comparisons per split. This design significantly reduces computational overhead while preserving preference discrimination. By combining DIANA-inspired cluster selection with preference-guided K-medoids splitting, the proposed clustering strategy reduces the number of required distance evaluations while preserving preference discrimination, making it suitable for dynamic MEC environments.
3.4. Task Allocation
The final stage of the proposed MCHC-TO framework is the task allocation, which integrates the outputs of the multi-criteria evaluation and the preference-driven hierarchical clustering stages to select the most suitable execution server for the incoming tasks. Algorithm 3 summarizes the complete decision process for each arriving task t, as illustrated in the red box of Figure 2.
Before any action is performed, the algorithm first initializes the required inputs and system parameters (see Algorithm 3, lines 1–3). First, the sensitivity and delay thresholds are loaded. Then, the set A of candidate ESs is constructed. For the incoming task t, the task descriptor is formed to capture its size and delay sensitivity, while the server descriptor stores the location and available capacity of each candidate ES. The thresholds and characterize the service sensitivity and delay tolerance of tasks and are derived from the application profiles defined in the simulation environment. These parameters guide whether tasks should remain within the edge domain or be forwarded to the cloud when edge resources are not suitable. This initialization ensures that both the multi-criteria evaluation and the hierarchical clustering stages operate on a consistent and up-to-date view of the task requirements and server states.
This algorithm then distributes tasks according to their computational demand and latency sensitivity. In general, tasks with higher computational demand and greater delay tolerance may be redirected to the cloud, while latency-sensitive tasks are prioritized for execution at the edge. Specifically, tasks whose computational requirement exceeds the threshold and whose delay sensitivity falls below the threshold are directed to the cloud, (see Algorithm 3, lines 4–5; Figure 2, step 3) thereby preserving edge resources for latency-critical workloads. When the edge layer is selected for execution, the algorithm identifies the most suitable execution cluster using PROMETHEE-based net flow scores and a divisive hierarchical clustering algorithm. The task is then assigned to the server within the optimal cluster (Algorithm 3, line 10). Although the simulation assumes a static set of ESs, the hierarchical structure allows the method to adapt to server unavailability by redirecting tasks to alternative servers within higher-level clusters, thereby maintaining service continuity.
| Algorithm 3 The Proposed MCHC-TO Orchestrator | |
| Input: task features ; server information ; thresholds | |
| Output: selected execution location (server): ES () or cloud | |
| Initialization Phase | |
| |
| |
| |
| Decision Phase | |
| |
| |
| |
| ▹ Algorithm 1 |
| ▹ Algorithm 2 |
| ▹ |
| |
| |
3.5. Computational Time Complexity
The computational complexity of the proposed MCHC-TO framework is determined by two main components: (i) the PROMETHEE-based multi-criteria evaluation stage (Algorithm 1), and (ii) the preference-driven divisive hierarchical clustering stage (Algorithm 2). Using the notation introduced in Section 3, let denote the number of edge servers, the number of criteria, the number of generated tasks, and the number of ESs with positive net flow values.
For each orchestration decision, PROMETHEE computes the net flow value for every server through pairwise comparisons. Since there are server pairs and each comparison involves K criterion evaluations, the time complexity of the PROMETHEE stage per decision is . As K is small and fixed in MEC orchestration scenarios, the CRITIC-based weighting introduces only negligible preprocessing overhead and does not affect the asymptotic complexity.
After computing net flow values, only servers in are considered for clustering, where and . At each splitting step, two medoids are selected based on the maximum and minimum net flow values, and each server in the current cluster is assigned by comparing its distance to these two medoids, requiring operations for a cluster C. In the worst case, highly unbalanced splits may occur, leading to recursive cluster sizes , which yields a total clustering complexity of .
Since the PROMETHEE evaluation and clustering procedure are executed once per arriving task, the per-task computational cost is
which simplifies to in the worst case. Over a scheduling horizon with tasks, the total computational cost becomes
As discussed in Section 3.1.2, orchestration operates within bounded control domains where n and K are constrained by infrastructure limitations. In practical edge clusters, n remains moderate and K is small, ensuring that the per-task computational overhead remains stable and predictable. For larger geographic areas, scalability is achieved through multiple orchestrators operating in parallel, each managing its local server subset. Consequently, for a fixed orchestration domain, the overall computational cost scales linearly with the workload , i.e., . Therefore, the proposed MCHC-TO framework exhibits linear scalability with respect to workload intensity in bounded MEC orchestration domains.
3.6. Illustrative Example of Edge Server Allocation
For simplicity, to illustrate the MCHC-TO workflow, we consider an example set consisting of six edge servers (ESs), each evaluated using two criteria, as reported in Table 3. This illustrative example is intentionally simplified to demonstrate the step-by-step computation of the PROMETHEE scores and the clustering procedure. The experimental evaluation presented in Section 4 uses the full MEC configuration with dynamically updated server states. The first criterion represents the available computational capacity of an ES, normalized in the range . For example, the capacity value for indicates that approximately of its resources are currently utilized, while remain available. The second criterion corresponds to the server location relative to the MD submitting the task. Two location categories are considered: on-site and off-site. This criterion is modeled using binary values, where 1 denotes on-site ESs and 0 denotes off-site ESs. This modeling assumption implies that all off-site servers experience identical transmission characteristics, involving a WLAN hop from the MD to the ER, followed by a MAN hop from the ER to the ES. In this illustrative example, strict preference thresholds are assumed by setting , such that any non-zero deviation between ESs leads to a strict preference. Using the CRITIC-derived weights, the PROMETHEE method is then applied to compute the net flow scores for all ESs, as reported in Table 3.
Table 3.
Illustrative example of edge servers, evaluation criteria, and resulting PROMETHEE net flow values.
Before applying PROMETHEE, the relative importance of the two criteria is determined objectively using the CRITIC method. CRITIC computes criterion weights based on their variability and inter-criteria correlation. Table 4 reports the standard deviations, correlation coefficient, CRITIC importance values, and the resulting weights for both criteria. As shown in the table, the location criterion receives a higher weight due to its larger contrast intensity and lower redundancy with the capacity criterion. The resulting CRITIC weights are for capacity and for location.
Table 4.
CRITIC weighting results for the illustrative example.
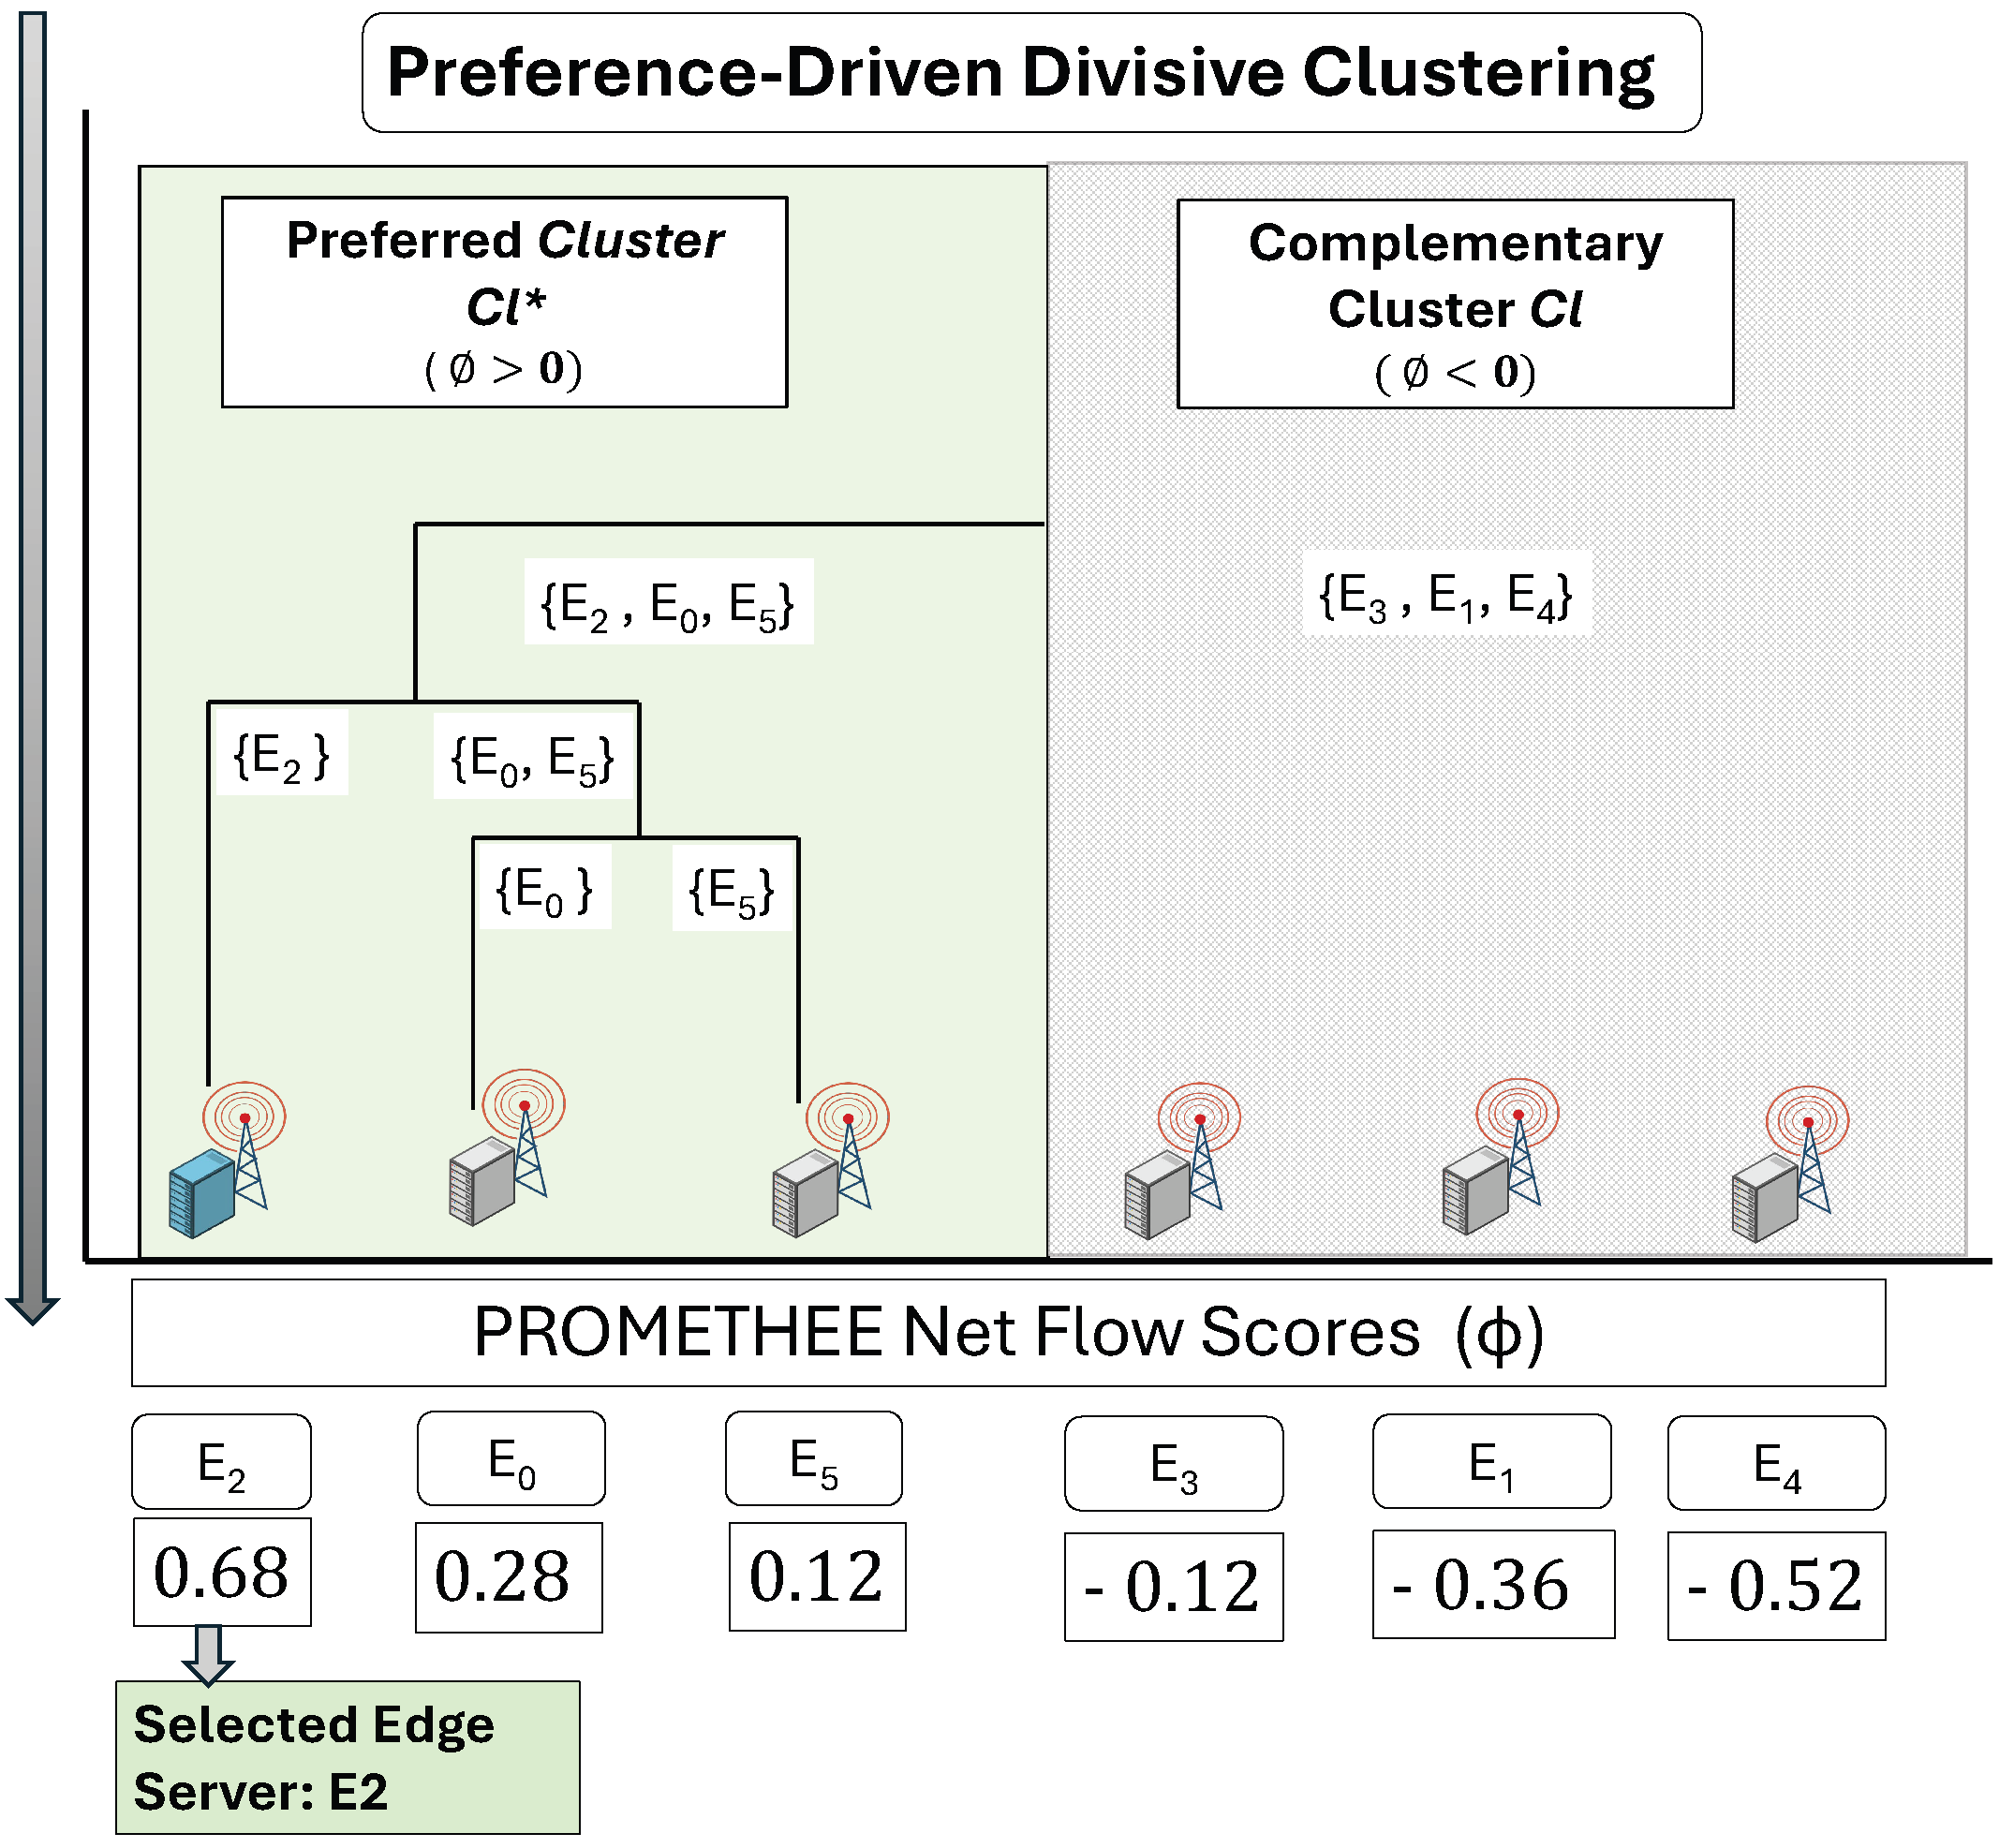
Figure 3 visually summarizes the evaluation, clustering and selection process described in this scenario. Based on the resulting net flow scores, MCHC-TO applies the preference-driven divisive hierarchical clustering process as follows:
Figure 3.
Illustrative example of PROMETHEE net flow evaluation and preference-driven divisive hierarchical clustering for edge server allocation.
- Step 1: Based on the net flow scores in Table 3, the set of ESs A is initially divided into two sub-clusters: a preferred cluster , containing servers with positive values, a and a complementary cluster containing servers with negative values. As illustrated in Figure 3, the preferred cluster is shaded in green, while is shaded in grey.
- Step 2: The preferred cluster , which contains the highest net flow value, is selected for further division using the preference-guided K-medoids splitting procedure ( in this case). The medoids are chosen as (highest ) and (lowest ). The remaining server is assigned to the nearest medoid, yielding two sub-clusters and .
- Step 3: The cluster , which still contained multiple servers, is divided further. New medoids were selected as and , resulting in two singleton clusters and . The recursive clustering process continues until all clusters contain exactly one ES.
Based on the requirements of the incoming task and the outcomes of the above clustering process, if the task is assigned to the edge layer, the ER selects cluster , which corresponds to the ES with the highest net flow score.
4. Performance Evaluation and Discussion
This section evaluates the performance of the proposed MCHC-TO solution in the MEC platform. This analysis employed the EdgeCloudSim simulator [35], a widely used simulation tool developed specifically to evaluate edge computing environments and their applications.
4.1. Simulation Setup
In order to simulate realistic edge computing environments, EdgeCloudSim integrates four representative application types: augmented reality (AR), infotainment (Info), health monitoring (HM), and compute-intensive (CI) applications [15]. Table 5 illustrates the key simulation parameters related to tasks. The usage percentage reflects the proportion of MDs associated with each application type, and the task inter-arrival time follows an exponential distribution to simulate task generation rates. Task generation follows an active/idle pattern, in which MDs produce tasks only during active periods. Each task is characterized by its length (in million/Giga instructions MI/GI) unit, determining the required CPU resources, with the execution time calculated based on the VM capabilities in GIPS. The delay-sensitivity scores reflect the importance of latency for a task, with higher values indicating greater real-time demands. The upload and download data sizes represent the volume of data exchanged with the servers during the task execution. Finally, the VM utilization denotes the proportion of CPU resources consumed when running tasks, which is essential to ensure the server can accommodate the task without failure.
Table 5.
Requirements of different tupes of applications.
The simulation environment included 14 ESs and a centralized cloud data center. Each ES is modeled as a Linux-based host (x86 architecture, Xen hypervisor) with 16 CPU cores (80,000 MIPS total capacity), 16 GB RAM, and 400 GB storage, running eight virtual machines (VMs). Each VM is configured with 2 CPU cores, 10,000 MIPS processing capacity, 2 GB RAM, and 50 GB storage. The cloud layer is modeled as a centralised data center with one host running four high-capacity VMs. Each cloud VM is configured with 4 CPU cores, 100,000 MIPS processing capacity, 32 GB RAM, and 1 TB storage. The network parameters, including the bandwidth and delay, were modelled empirically based on real-world observations, as proposed in [15]. The WAN propagation delay was set to 100 ms, while the LAN internal delay was set to 5 ms. A nomadic mobility model governed the movement of 200 to 2400 MDs across three location types, with equal transition probabilities and dwell times of 2, 5, and 8 min, representing varying levels of location attractiveness [35]. This configuration resulted in approximately 6600 to 75,000 tasks generated during the simulation runs. The broad MD density range enables evaluation under both moderate and highly congested conditions. Higher densities intensify competition for limited edge resources, thereby challenging orchestration decisions and providing a robust evaluation environment.
All simulations were executed on a Windows-based workstation equipped with an Intel Core i7 processor and 16 GB RAM. Each simulation scenario is executed for 40 independent runs to account for stochastic variations in task generation, mobility, and network conditions. In each run, the simulation duration is 5 min, including a 1-min warm-up period during which system statistics are not recorded. All reported performance metrics correspond to the average values across these runs.
4.2. Comparison Algorithms
To ensure a comprehensive and fair evaluation, the proposed MCHC-TO framework is compared with representative MEC orchestration strategies that span different decision paradigms, including clustering-based, multi-criteria decision-making, learning-based, and heuristic approaches. In order to evaluate the proposed solution, we implemented several baseline methods within the same simulation environment, including single-criterion clustering methods, the Fuzzy Logic-based Task Orchestrator (FL-TO) [15], and a DRL-based algorithm (DeepEdge) [18]. In our evaluation, we developed two versions of K-medoids-based single-criterion clustering algorithms to compare them with the proposed multi-criteria clustering approach: location-based clustering for task orchestration (LOC-TO) [36], and server-capacity-based clustering for task orchestration (CAP-TO).
To further strengthen the evaluation and quantify the benefits of intelligent orchestration over simple decision policies, two lightweight heuristic baselines were also implemented: Nearest Edge Server (NES), which selects the closest edge server, and Random Edge Server (RES), which randomly selects an edge server for task execution.
4.3. Simulation Results
In order to illustrate the effectiveness of the proposed MCHC-TO, we compared its performance against the comparison algorithms using the following evaluation metrics: (i) average service time, (ii) average failed tasks rate, and (iii) average CPU utilization. Before presenting the full comparison, we first examined the impact of different weight combinations for the defined PROMETHEE criteria on the system performance outcomes. These are presented in the following section.
4.3.1. Weight Determination and Sensitivity Analysis
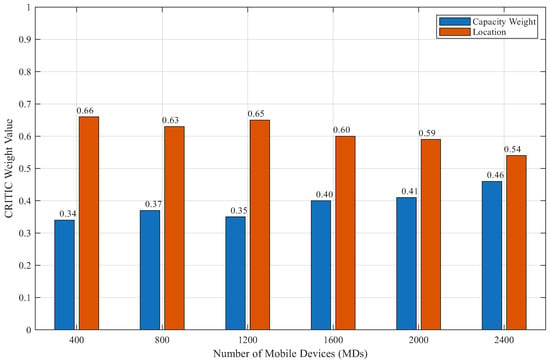
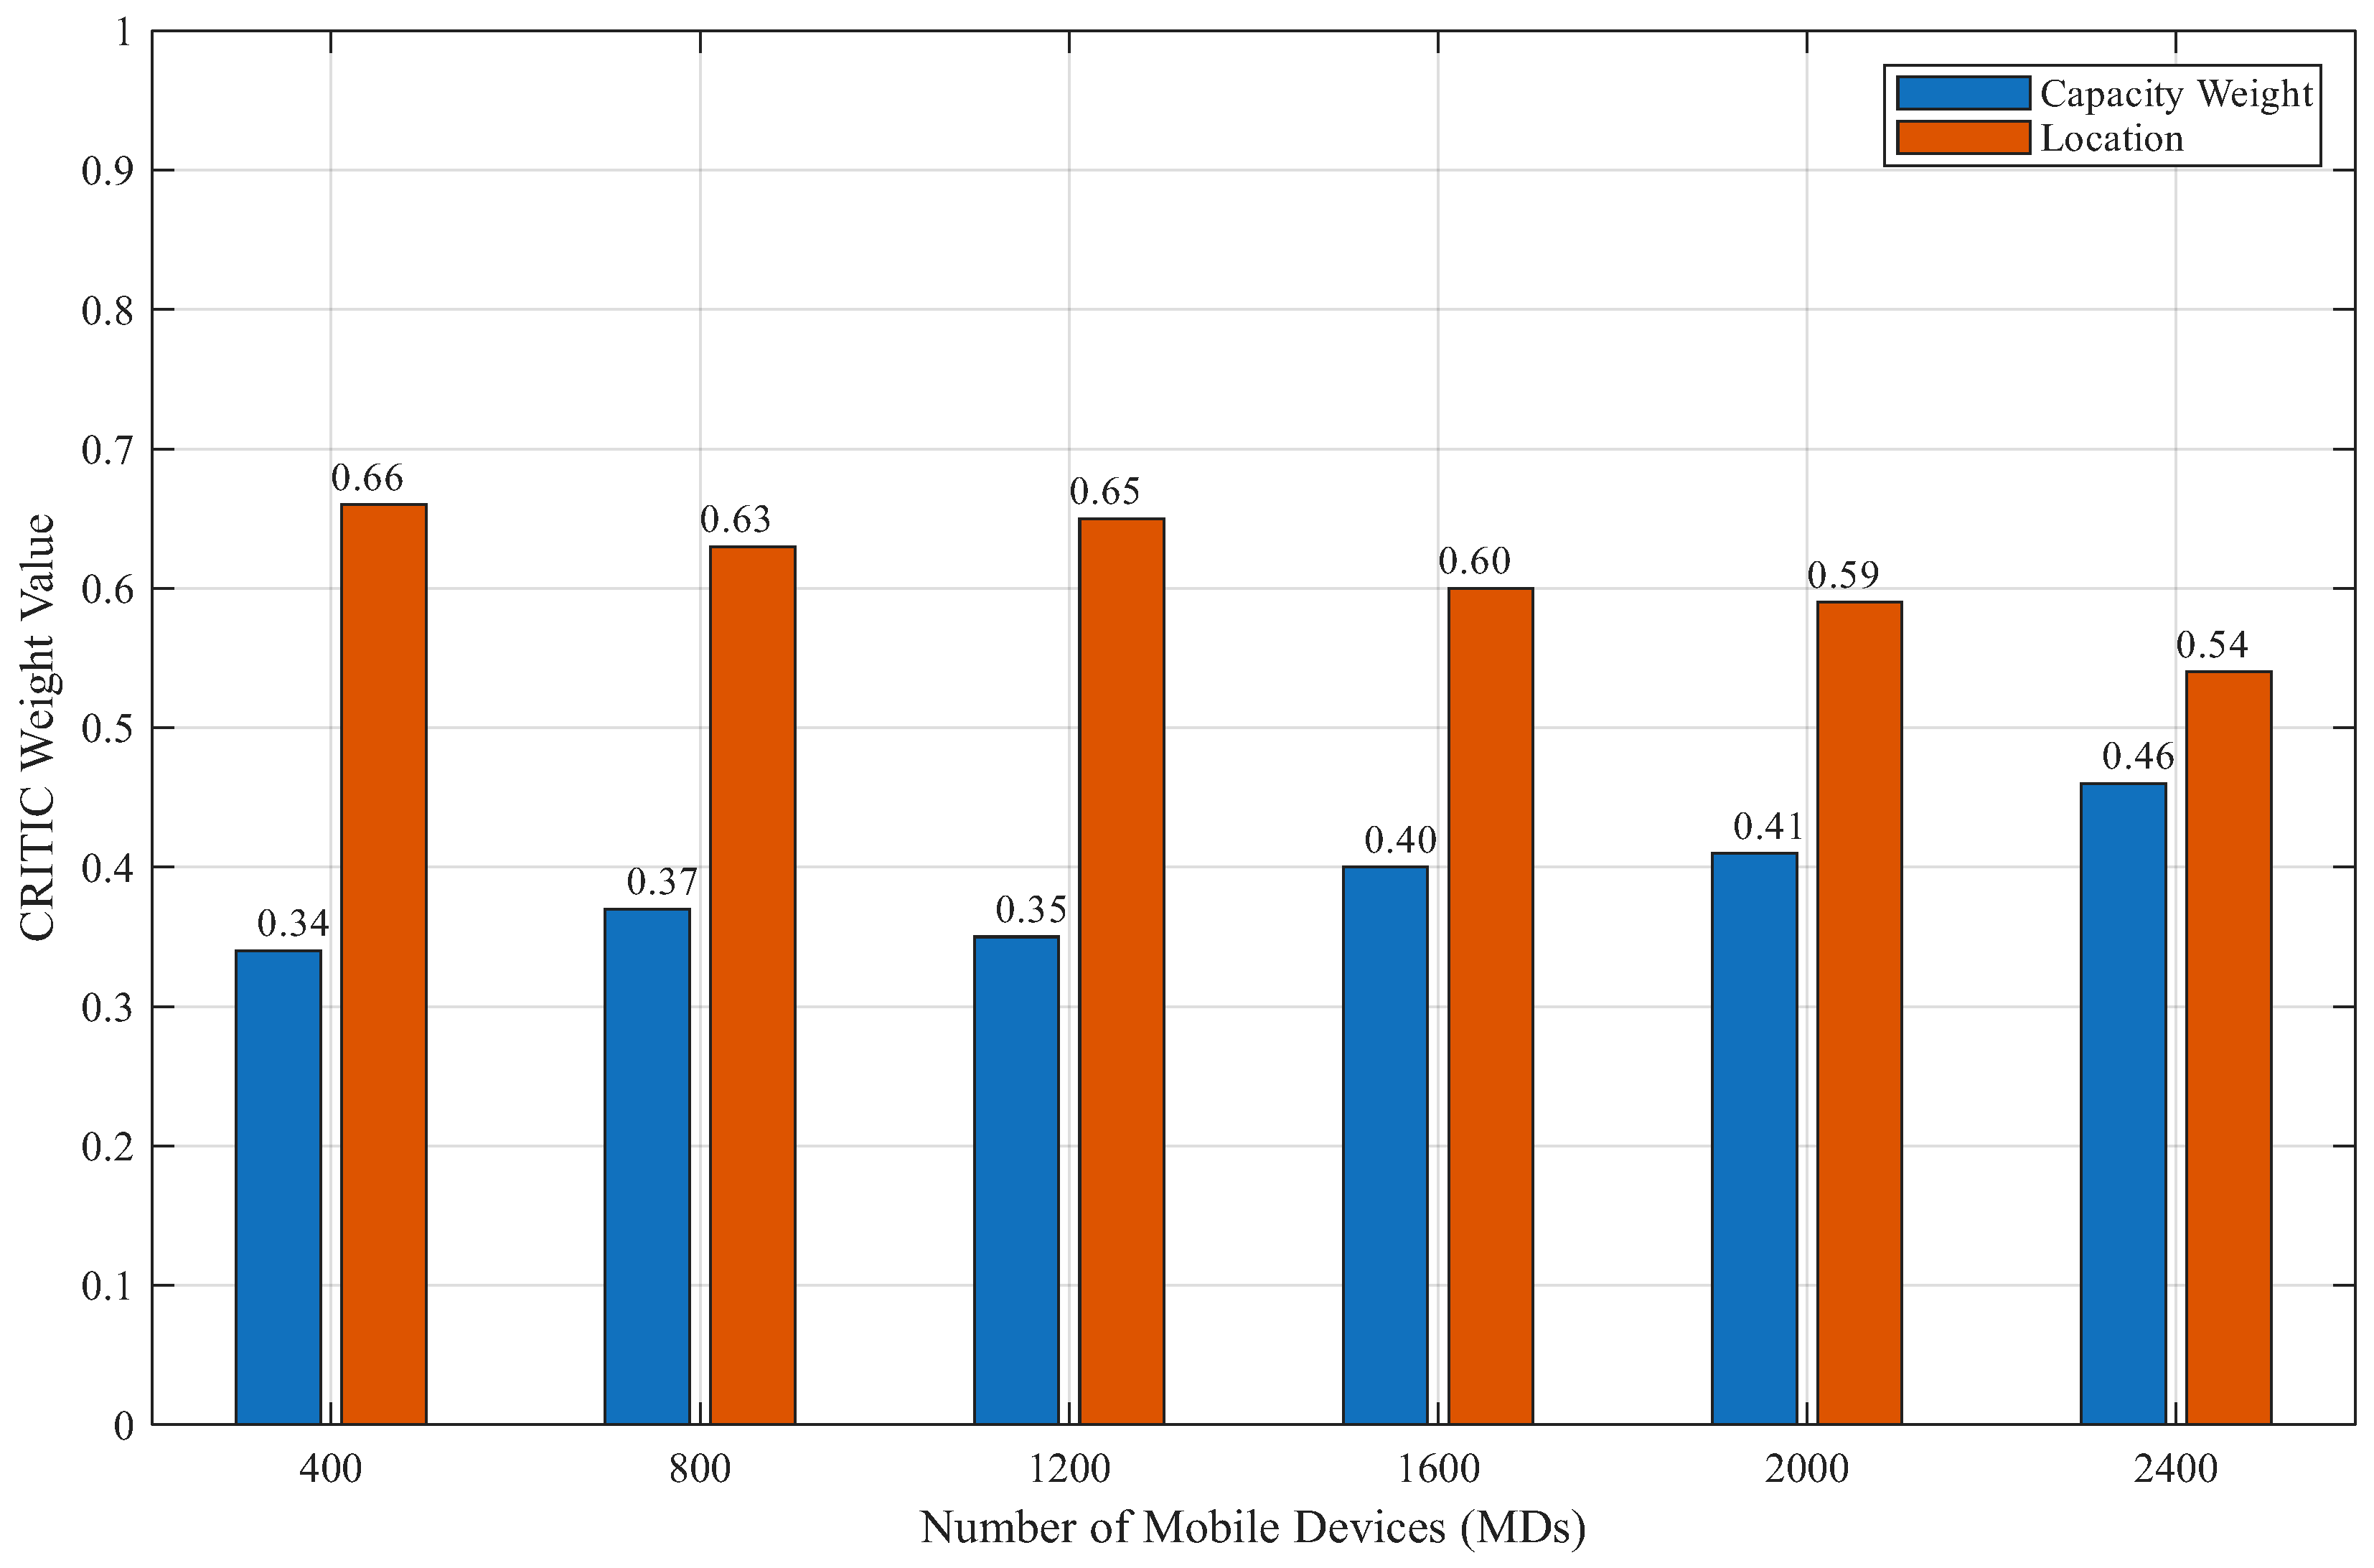
To establish an objective baseline for the relative importance of the capacity and location criteria, denoted by and , respectively, we first applied the CRITIC method to the simulation-generated decision matrix, as described in Section 3.2.2. The resulting CRITIC-derived weights across different workload levels are illustrated in Figure 4, where the normalized workload level represents the ratio of the current workload to the maximum workload considered in the simulations. The figure indicates that the location criterion consistently receives a higher weight than the capacity criterion. Therefore, the location contributes more strongly to distinguishing among candidate servers in the considered MEC environment. As the workload increases, the weight assigned to capacity gradually rises while the weight of location decreases, reflecting the growing relevance of resource availability under higher system load. This transition reveals an optimal region between and , where balanced consideration of proximity and resource availability yields the most effective performance. Notably, both weights remain within a relatively narrow range across all workloads, indicating a smooth, workload-aware shift rather than sudden or unbounded changes.
Figure 4.
CRITIC-derived weights of capacity and location criteria under increasing workload.
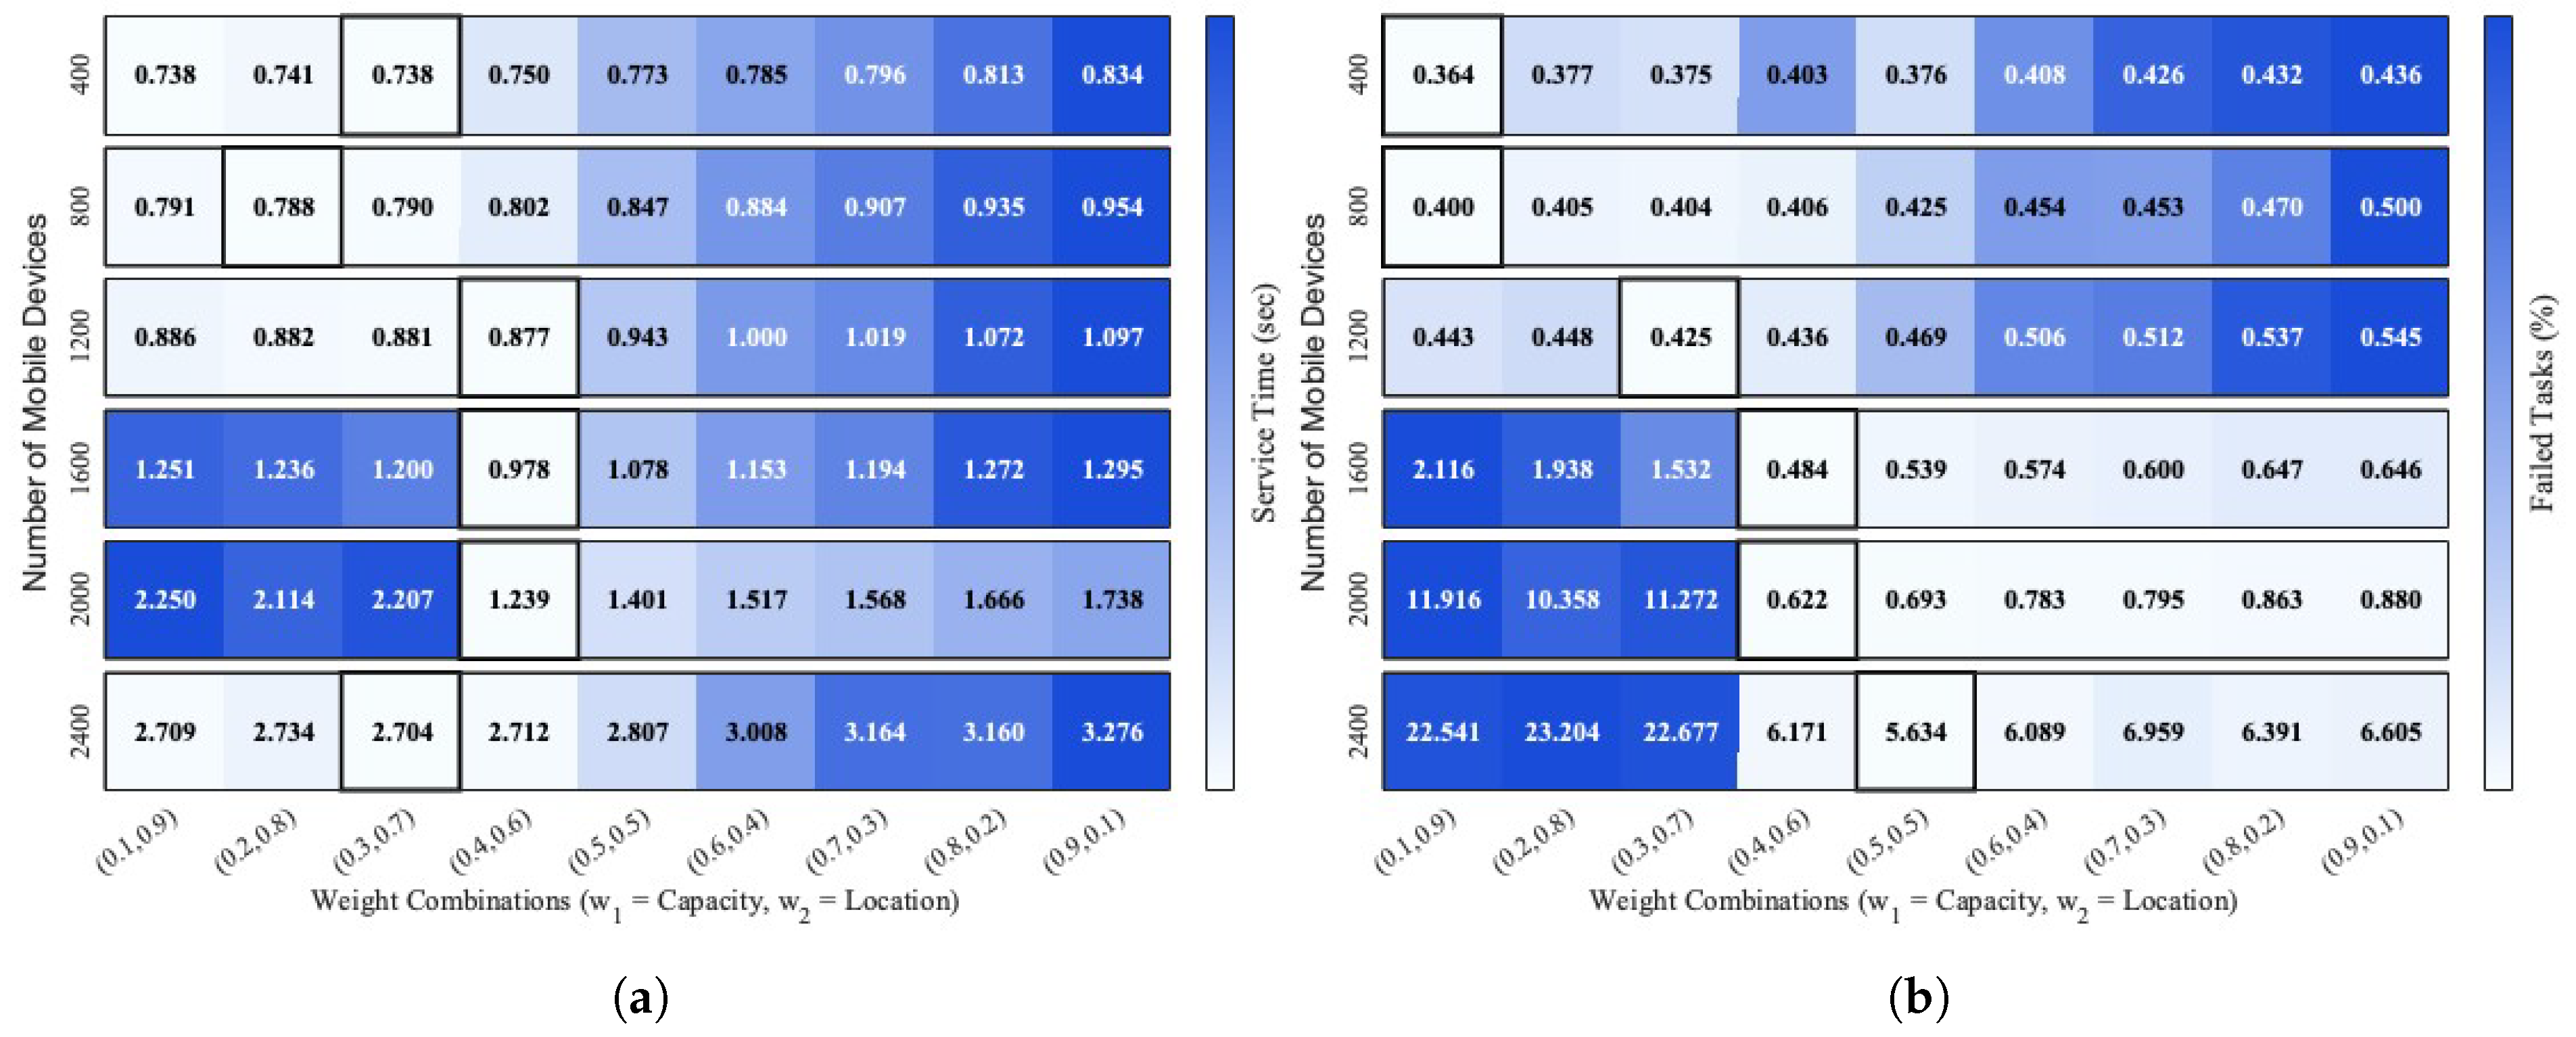
While CRITIC provides an objective, data-driven estimate of criterion importance, it does not directly optimize system-level performance metrics. Therefore, to validate and refine the weight selection, we conducted a sensitivity analysis by evaluating several representative weight combinations under varying system loads. The performance of each combination was assessed using two key metrics: average service time and average task failure rate. To visualize the impact of different weight combinations across varying workload levels, Figure 5 presents heatmaps of average service time and task failure rate. In each heatmap, rows correspond to different workload levels, while columns represent the evaluated weight combinations. The row-separated layout enables clear comparison of performance trends across workloads.
Figure 5.
Effect of weight combinations on (a) average service time and (b) average task failure rate, shown as row-separated heatmaps, where each row corresponds to a fixed workload level.
Figure 5a illustrates that the weight combination minimizing service time varies with the workload level and does not follow a single monotonic trend. Under light workloads (400–1200 MDs), the minimum service delay is achieved by different weight combinations across rows; however, all of them are location-dominant, such as , , , and . The results suggest that when edge resources are underutilized, prioritizing proximity reduces service times effectively. As the workload increases to moderate levels (1600–2000 devices), the optimal region stabilizes around . Strongly location-dominant combinations begin to incur higher delays due to local edge server saturation, while capacity-dominant configurations suffer from increased offloading to remote edge servers or the cloud. This highlights the need to balance proximity with resource availability once contention emerges. Under the heaviest workload (2400 devices), the overall service delay increases substantially for all weight combinations, reflecting system-wide congestion. Although a location-dominant configuration again yields the lowest delay in this extreme case, the differences among weight combinations become less noticeable as congestion dominates system behavior. Importantly, across all workload regimes, the weight combination consistently remains near-optimal and never incurs severe performance degradation. This robustness motivates its selection as the default setting in the proposed MCHC-TO framework, providing stable performance across diverse and dynamically changing load conditions.
Figure 5b complements the service-time analysis by illustrating how task failure rate evolves under different weight combinations and workload levels. Under light workloads (400–1200 devices), failure rates remain uniformly low across all configurations. As the workload increases, strongly location-dominant combinations experience a noticeable rise in failure rate due to on-site server overload. This increase in failure rate is consistent with the service-time behavior shown in Figure 5a, where strong location dominance leads to on-site ES saturation and subsequent task redirection to the cloud. In contrast, balanced configurations such as maintain lower failure rates and more stable service performance. Together, the service-time and failure-rate heatmaps demonstrate that robust task orchestration in MEC is workload-dependent and requires balancing proximity-driven latency reduction against failure-induced delay amplification, particularly under moderate to heavy workloads.
This experimental finding is further supported by the CRITIC-derived objective baseline, which assigns higher importance to the location criterion under light workloads and gradually increases the relative weight of capacity as the system load grows. The close alignment between the CRITIC-based weighting trend and the empirically observed balance point around confirms that the selected weight configuration captures the intrinsic workload-dependent trade-off between latency reduction and failure avoidance, rather than reflecting arbitrary parameter tuning.
4.3.2. Average Service Time
Service time is one of the most significant performance metrics, specifically for delay-sensitive applications. In our simulation, the service time of a task is defined as the total time elapsed from task submission to the reception of the execution result at the MD. Formally, the service time of task , denoted by , is computed as
where represents the task offloading delay over WLAN, MAN, or WAN, denotes the execution time on the selected ES or cloud server based on the allocated VM processing capacity, and corresponds to the result transmission delay back to the MD. The average service time is calculated over all successfully completed tasks as
where denotes the total number of successfully completed tasks during the simulation.
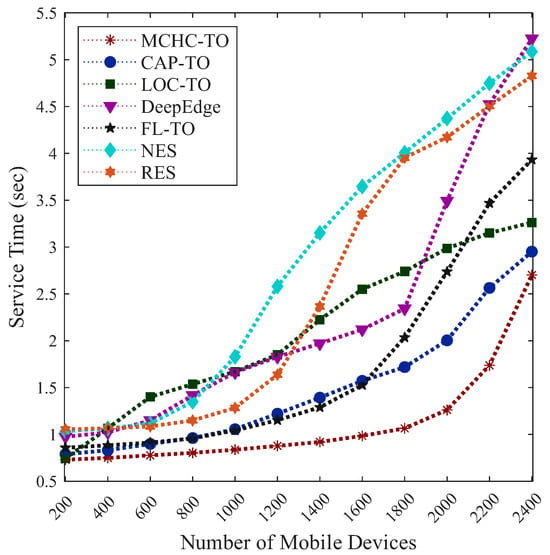
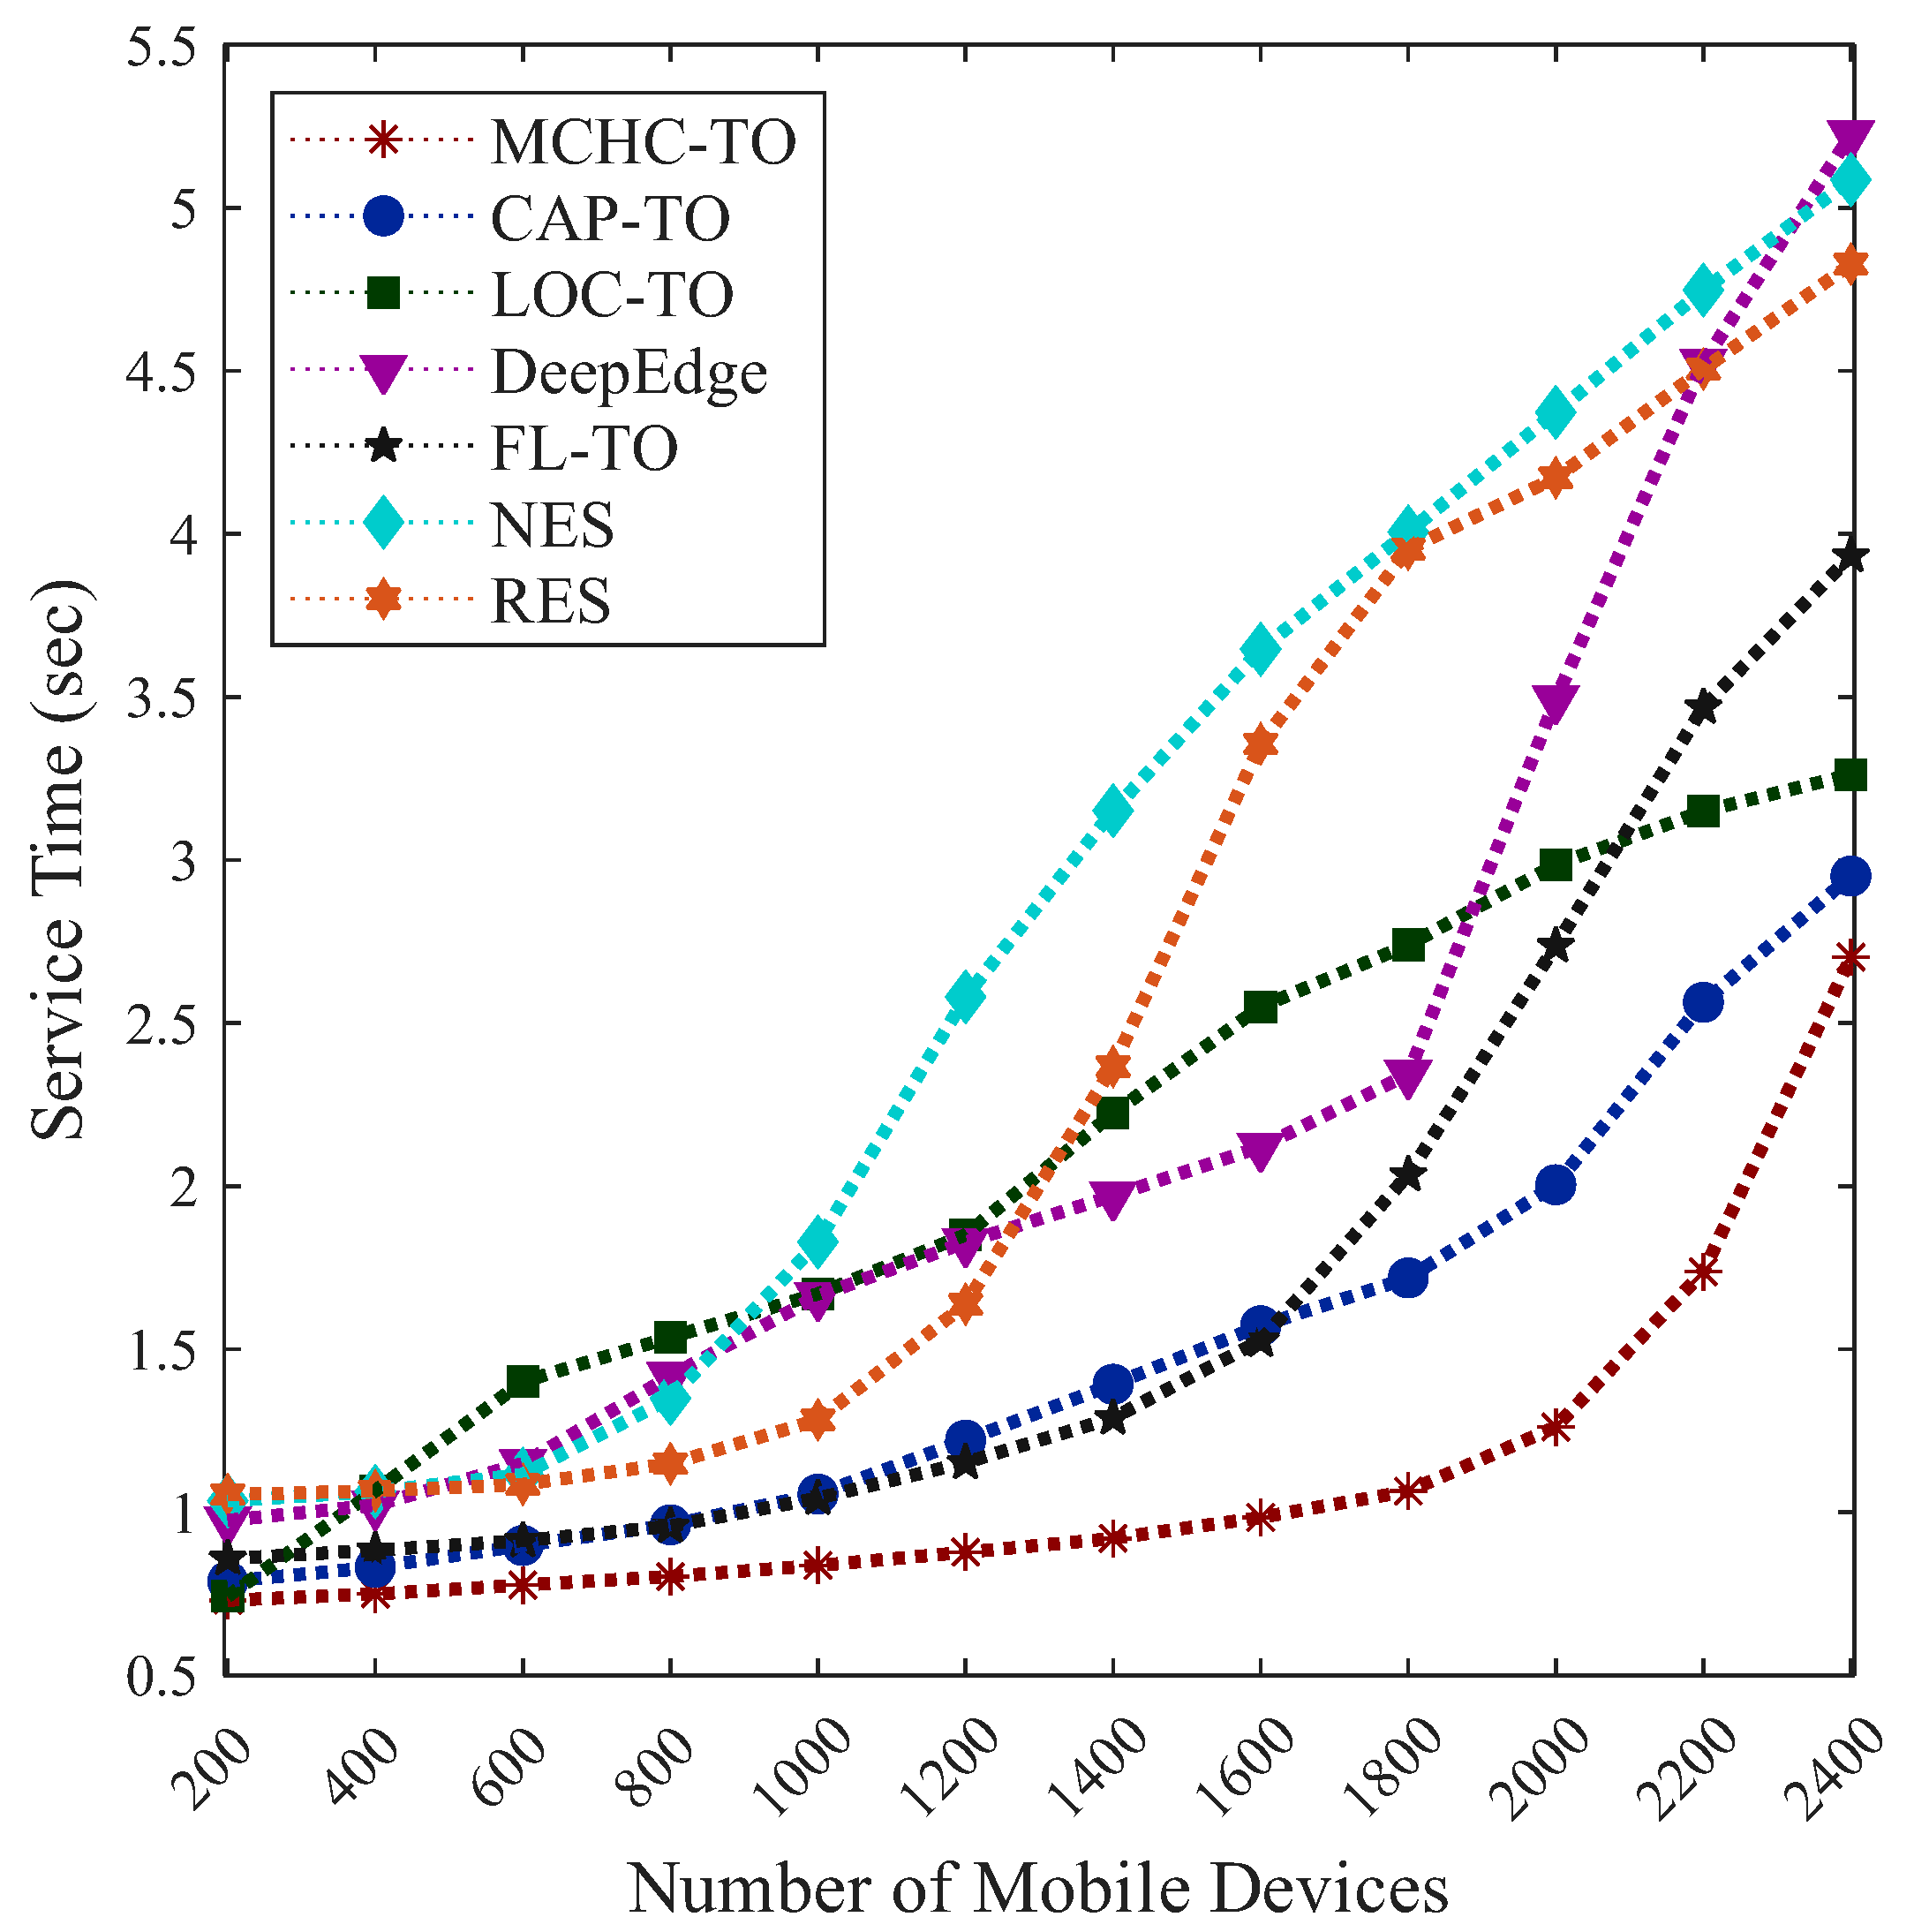
As shown in Figure 6, the average service time (combining both edge and cloud delays) increases as the number of MDs rises from 200 to 2400. The proposed MCHC-TO consistently outperformed the other algorithms, maintaining the lowest service time across all of the device counts. This demonstrated its ability to efficiently manage both the computational and network resources efficiently, while balancing the load between the edge and cloud layers. Beyond 1800 devices, FL-TO and DeepEdge exhibited sharp increases in service time, eventually exceeding LOC-TO. This indicated that DeepEdge and FL-TO consumed edge resources over cloud resources excessively, particularly when the system was overloaded. Meanwhile, CAP-TO achieved relatively low service delays because it formed clusters based on server capacity, consistently targeting the least-loaded servers in task allocation. In contrast, LOC-TO often overlooked the off-site servers that may had available capacity and focused primarily on the on-site servers, reducing the overall resource efficiency. The heuristic baselines NES and RES exhibited higher service times, particularly under high workload levels. NES selects the nearest edge server without considering server load or capacity, which often leads to congestion at popular servers. Similarly, RES randomly selects servers without considering resource availability, resulting in inefficient task placement and increased service delays.
Figure 6.
Comparative evaluation of average service time achieved by MCHC-TO and existing task orchestration methods under different workload levels.
4.3.3. Average Failed Task Rate
The task failure rate was another critical performance indicator. In our simulation, a task may fail for one of three main reasons, each determined by specific system conditions during execution: (i) Mobility-related failure occurs when the MD moves out of the coverage range of the serving access point before task completion and the MD receives the task response. (ii) Insufficient ES capacity is triggered when the selected ES lacks the available VM resources (i.e., MIPS) required to execute the task at the time of allocation. (iii) Network-capacity failure arises when the WLAN, MAN, or WAN cannot provide the necessary bandwidth for task offloading or result retrieval, typically due to congestion in the corresponding network segment.
The task failure rate is defined as
where is the number of failed tasks due to mobility, insufficient server capacity, or network limitations, and denotes the number of successfully completed tasks.
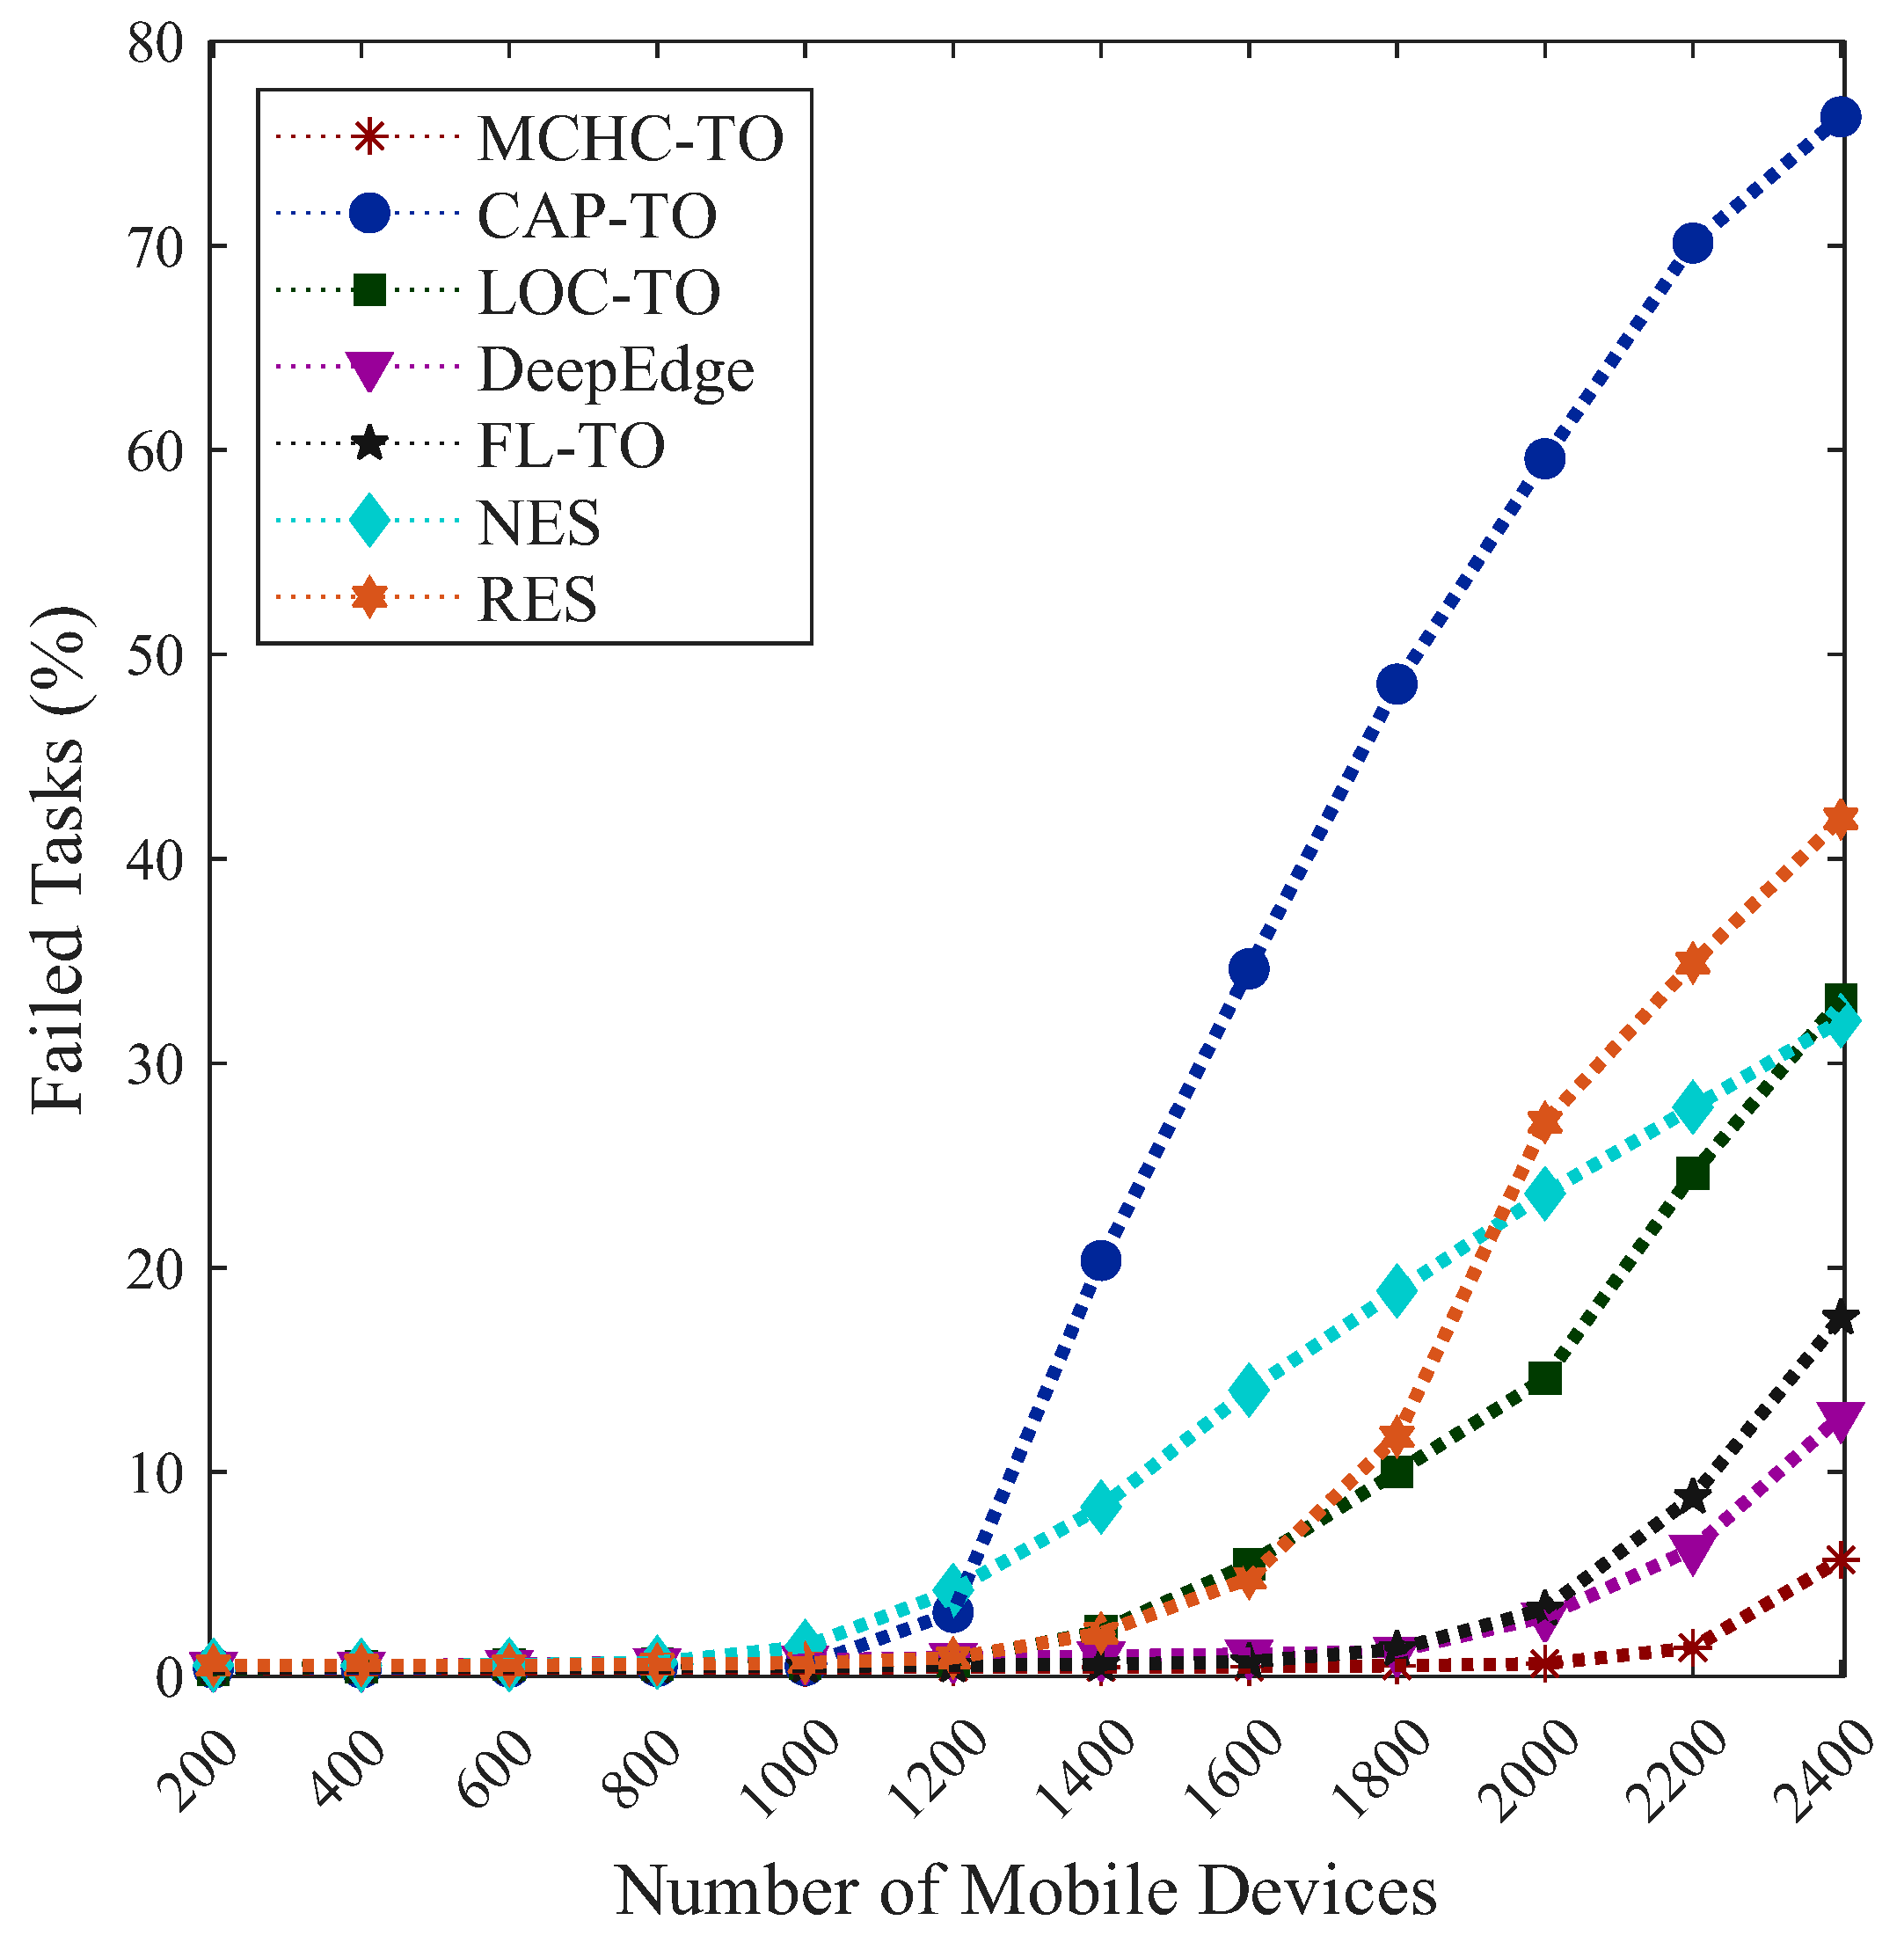
As shown in Figure 7, all approaches maintained failure rates below under light workload conditions (fewer than 400 MDs), but experienced significant increases as the system became overloaded. The proposed algorithm, MCHC-TO, consistently achieved the lowest task failure rate across all of the device counts, highlighting its adaptability in dynamic and congested environments (only under 2400 MDs generating approximately 75,000 tasks). In contrast, CAP-TO exhibited the highest failure rate, exceeding at peak load, indicating that its capacity-focused clustering strategy struggled to handle growing demand effectively. In addition, LOC-TO also exhibited noticeable increases in failure rate under a high load (around ), whereas FL-TO and DeepEdge maintained significantly lower failure rates ( and , respectively), demonstrating their stronger scalability and more balanced task distribution. The heuristic baselines NES and RES also experienced noticeable increases in failure rates as the workload intensified. Under the highest load (2400 MDs), NES reached approximately failed tasks, while RES exhibited a sharp increase after 1800 devices, reaching about at peak load. Overall, it can be concluded that single-criteria or heuristic task orchestration strategies lead to a high number of failed tasks as the load increases, primarily due to the inability to balance and trade off among critical criteria.
Figure 7.
Comparative evaluation of average failed tasks achieved by MCHC-TO and existing task orchestration methods under different workload levels.
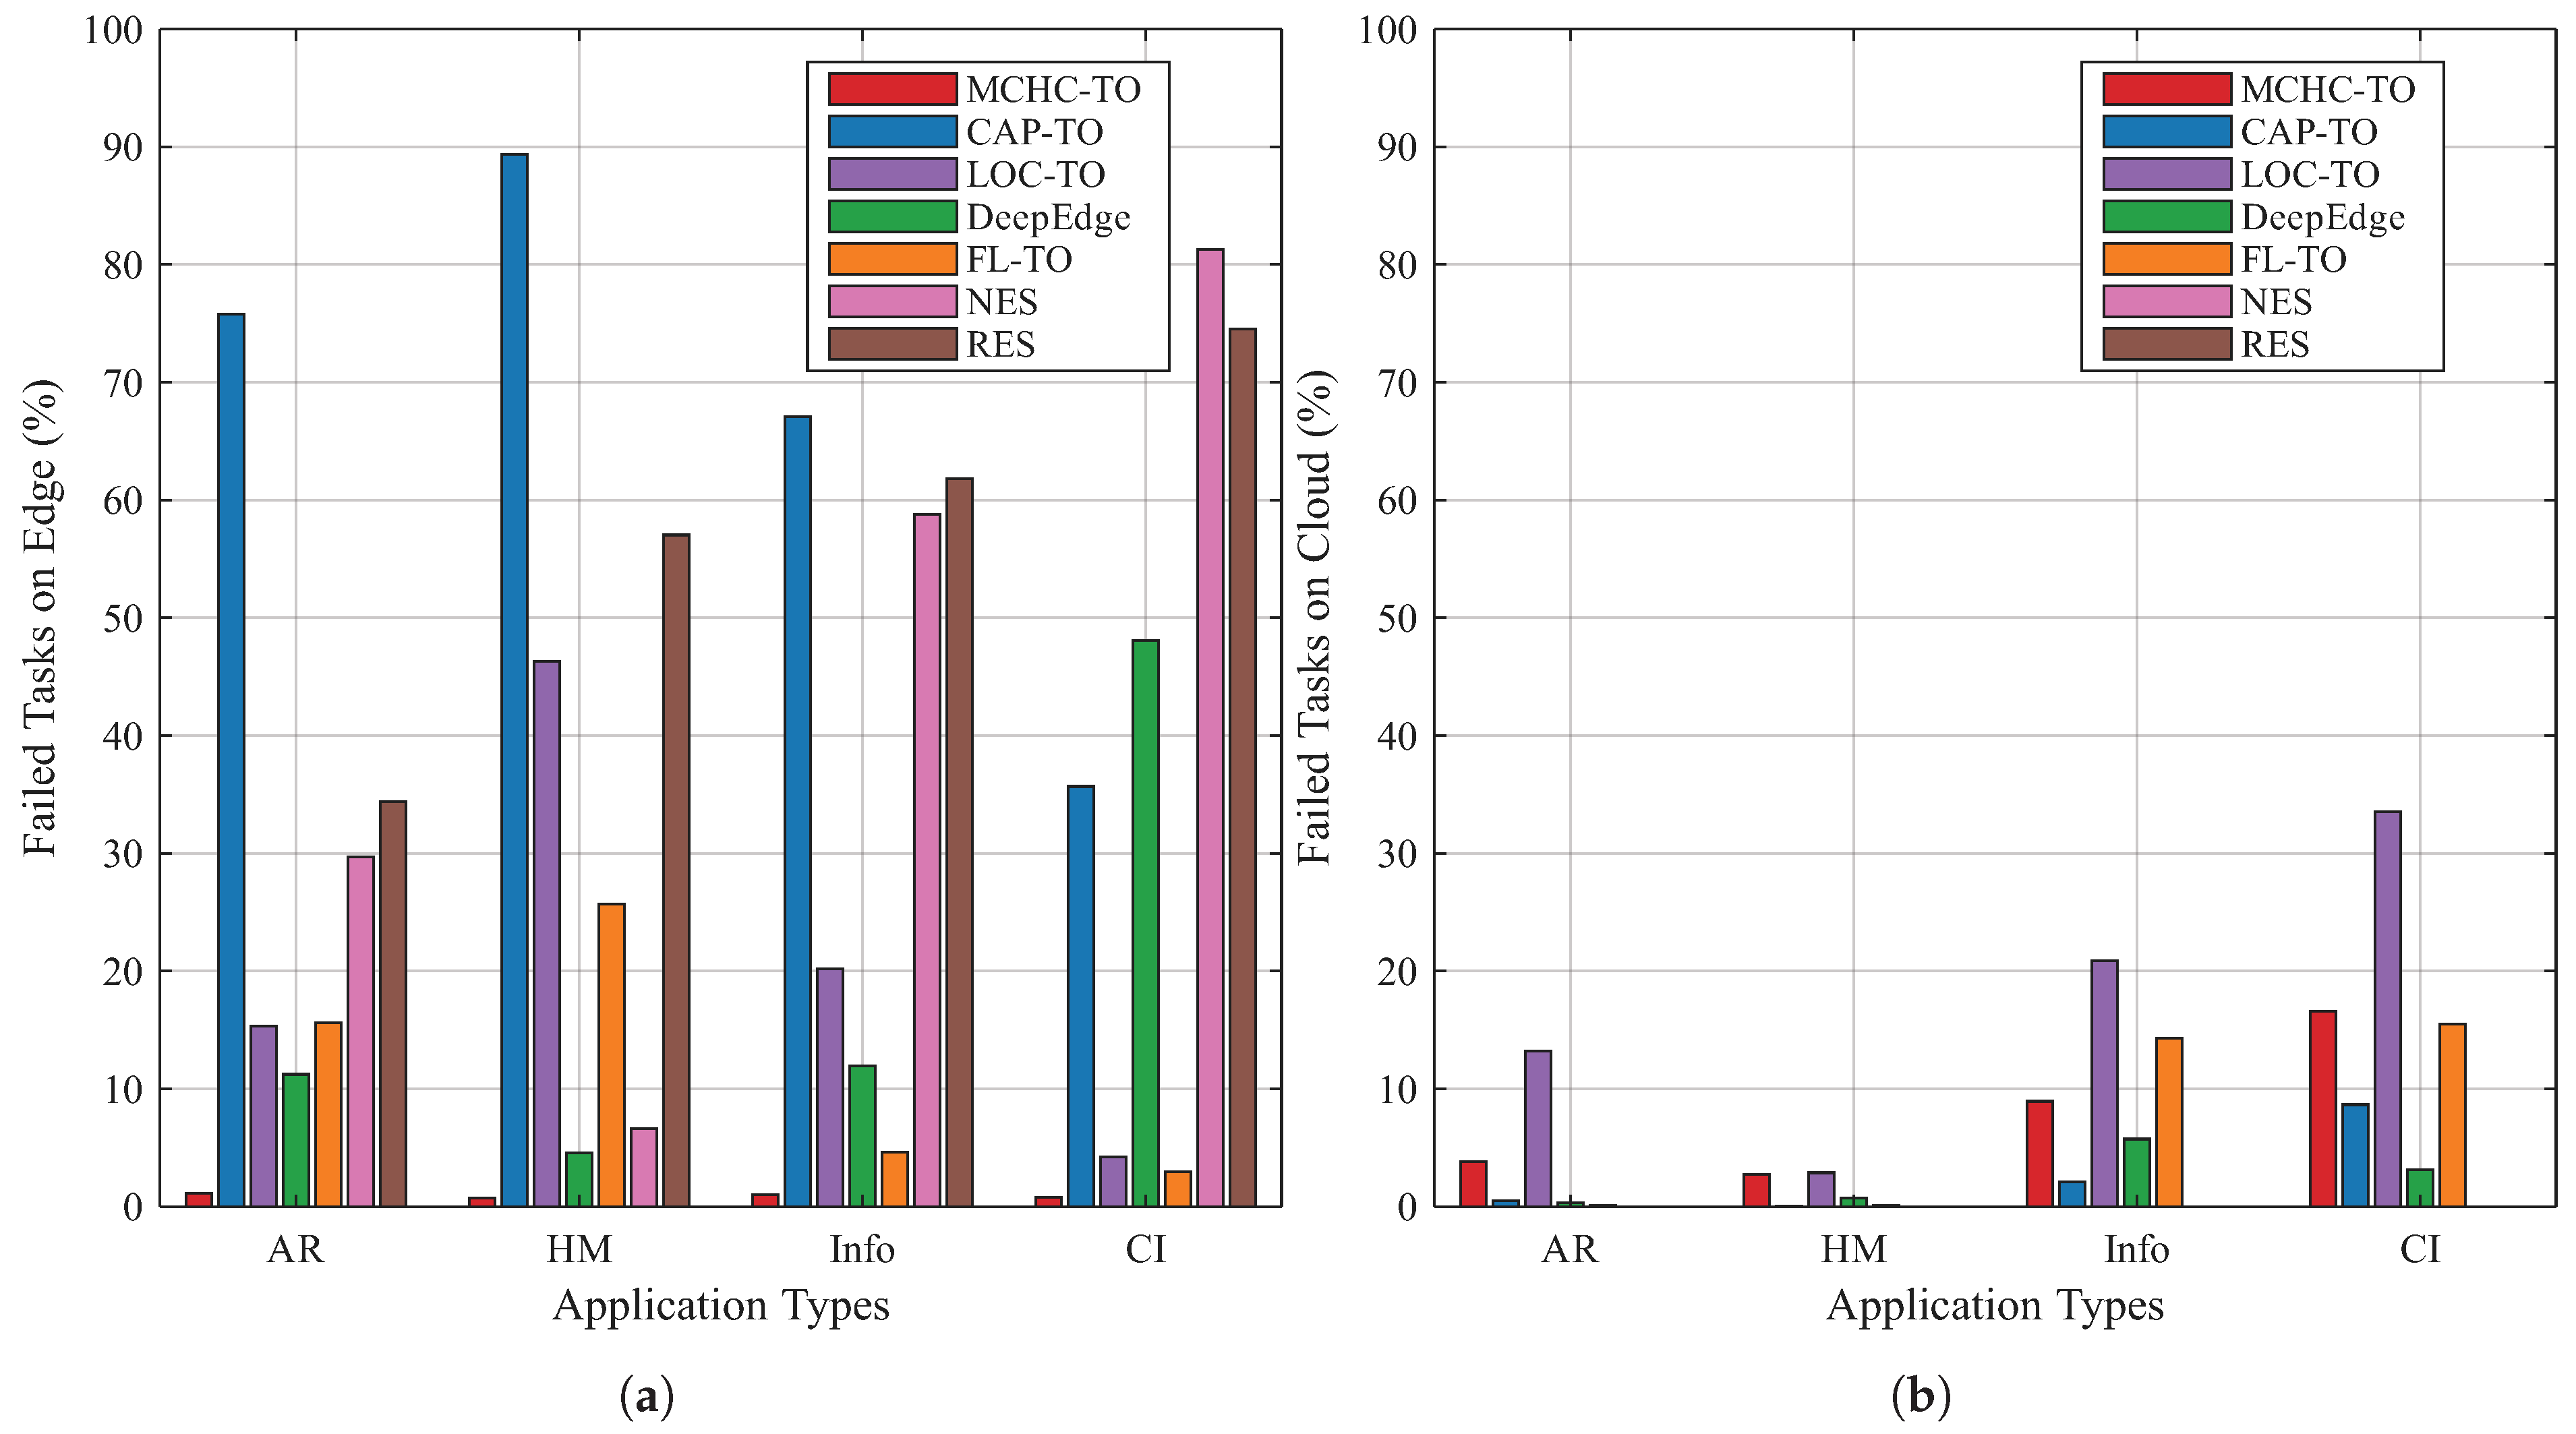
Figure 8 details the failure rate by application type for each algorithm at peak load (2400 MDs) on the edge and cloud layers. Under this highly dense workload condition, MCHC-TO, LOC-TO and FL-TO exhibit the higher failure rates for CI applications. CI tasks are delay-tolerant and involve large workloads requiring approximately CPU utilization on edge VMs but only on cloud VMs. Consequently, these orchestrators preferentially offload CI tasks to the cloud to avoid edge resource congestion, which increases WAN bandwidth consumption and may lead to network-related failures, as shown in Figure 8b. Similarly, DeepEdge exhibits elevated CI failures at the edge layer because it attempts to allocate these large tasks on limited edge resources (Figure 8a). In addition, CAP-TO showed a high failure rate with the HM application, which generates delay-sensitive, small-sized tasks at a high rate (every three seconds). These tasks are preferentially executed at the edge; however, the high arrival rate creates resource contention and bottlenecks when load balancing is insufficient, resulting in increased edge-layer failures. The heuristic baselines NES and RES also exhibit considerable edge-layer failures across several application types, particularly for CI workloads, because their simple server selection policies do not consider both proximity and available computational capacity, leading to inefficient task placement under high workload conditions.
Figure 8.
Average failure rate of MCHC-TO across different application types at: (a) edge layer, and (b) cloud layer.
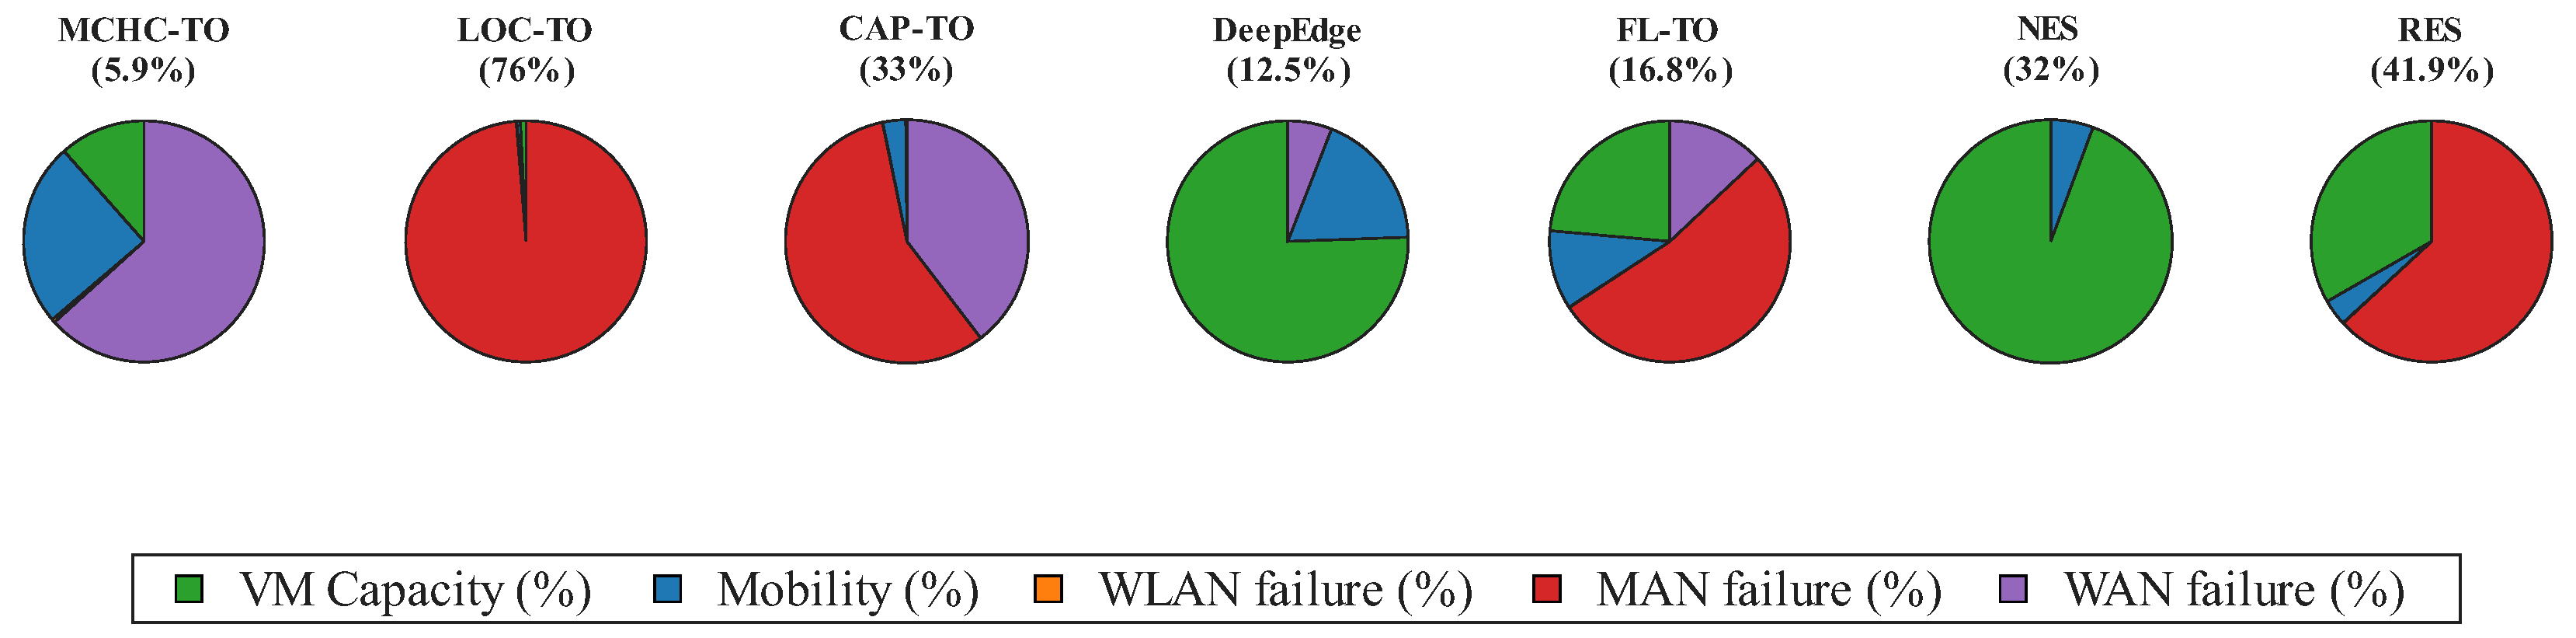
The distribution of task failure reasons for all of the algorithms at the highest system load (2400 devices) is illustrated in Figure 9. For MCHC-TO, the most dominant cause for the failed tasks () was WAN-related delay, which accounted for over half of the total task failures. This indicated that, under extreme load, some tasks were still offloaded to the cloud due to limited edge capacity, resulting in higher latency. In contrast, CAP-TO failures are dominated by MAN delay because its capacity-based selection frequently routes tasks to off-site edge servers, requiring transmission through the shared MAN network under congested conditions. LOC-TO also exhibits a high proportion of MAN failures, as proximity-based grouping still forward tasks to neighbouring RANs under high-density workloads, resulting in MAN traversal when local servers become overloaded. FL-TO presents a mixed failure profile; although it considers multiple decision factors, its rule-based decisions may still route tasks to remote edge servers under heavy load, leading to MAN delays in addition to capacity-related failures. DeepEdge failures, in contrast, are primarily capacity-related, reflecting its tendency to aggressively allocate tasks at the edge layer, which can overload edge servers under high demand. Similarly, NES and RES failures are mainly associated with capacity and network delays because their heuristic selection strategies do not explicitly balance resource availability and communication cost.
Figure 9.
Distribution of failure reasons of the proposed solution MCHC-TO.
4.3.4. Average CPU Utilization
The average CPU utilization reflects how intensively the available VM resources are used across the edge layer. In our simulations, all compared algorithms employ the same number and configuration of VMs per edge server. Therefore, average CPU utilization primarily reflects the overall loading of the edge layer rather than differences in resource availability. Lower utilization accompanied by reduced service delay and failure rate indicates more balanced task allocation and alleviated congestion across edge servers. In contrast, high utilization values may imply either effective resource exploitation or server overload, depending on the resulting system performance.
Formally, the average CPU utilization across the edge layer is computed as
where A denotes the set of edge servers, and and represent the utilized and available processing capacity of server a, respectively.
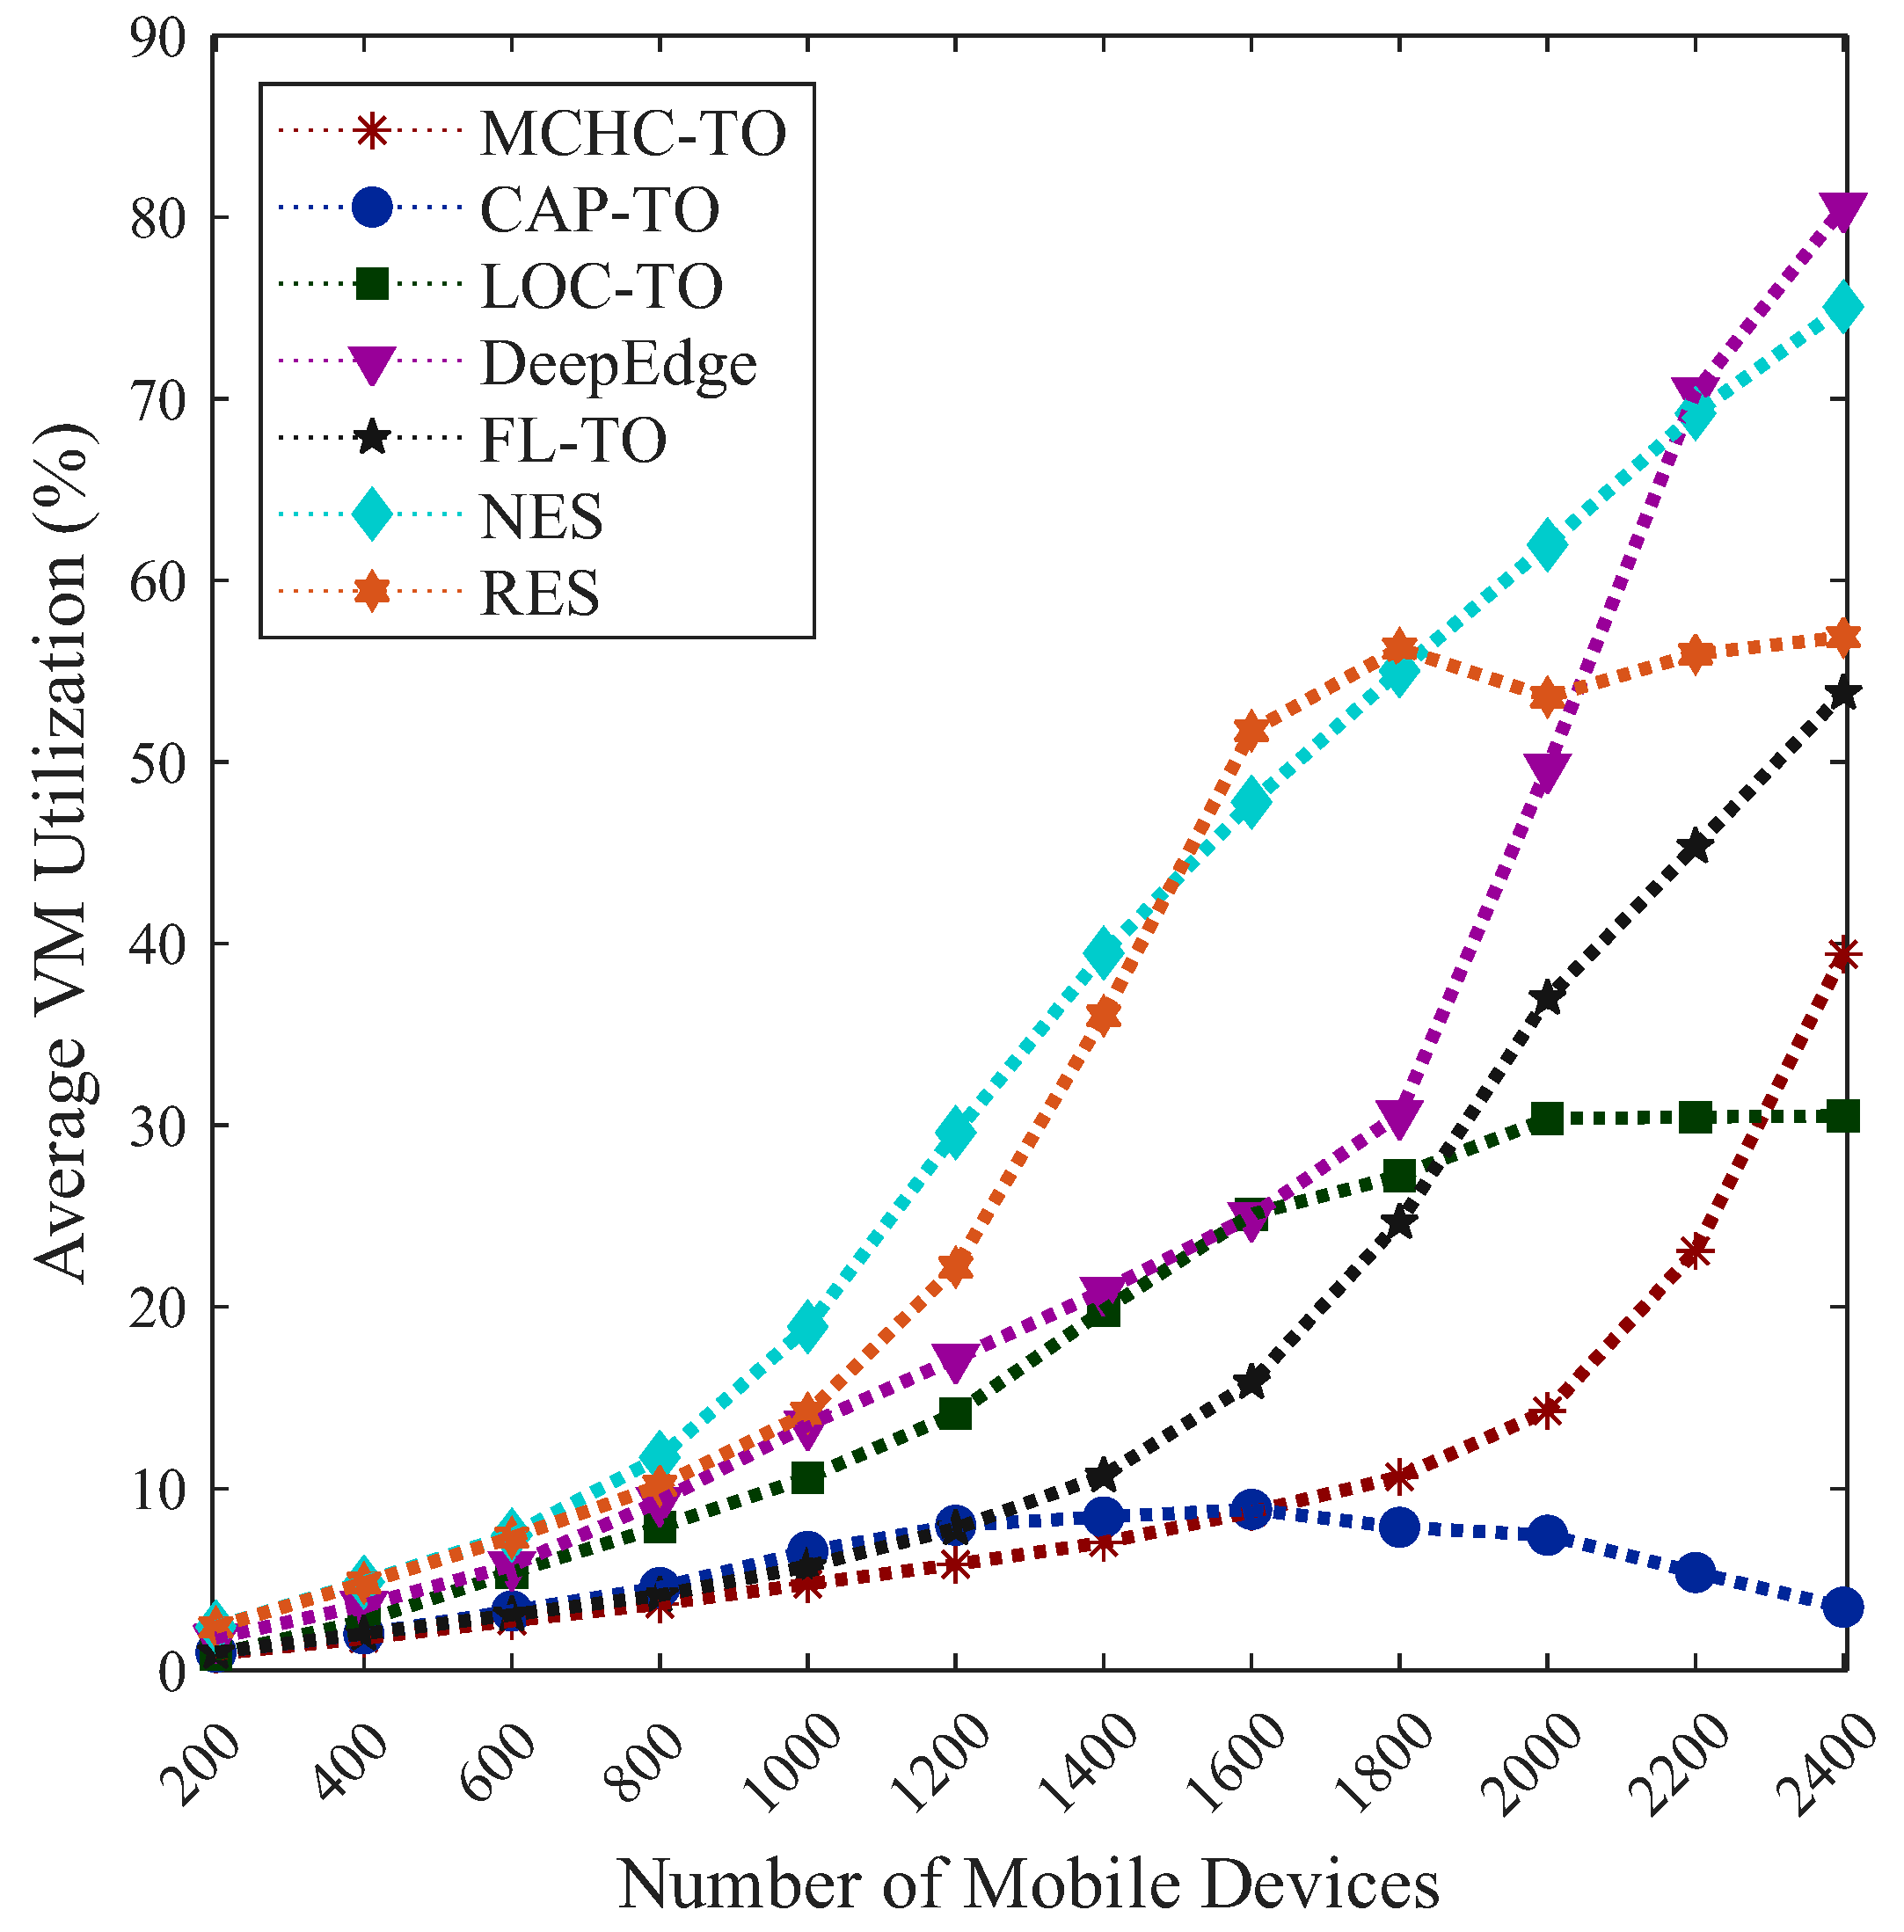
Figure 10 illustrates the average CPU utilization of VMs across all the ESs as the number of MDs increased. For most algorithms, the average CPU utilization increases with the number of MDs, indicating higher resource demand. However, CAP-TO and RES exhibit different trends. In the case of CAP-TO, the utilization initially rises up to around 1200 MDs and then declines for higher loads. Similarly, RES increases up to approximately 1800 MDs before slightly decreasing at higher workloads. This reduction is attributed to the high task failure rates caused by MAN-related delays for both solutions, as shown in Figure 7, which results in fewer tasks being successfully executed at the edge layer.
Figure 10.
Comparative evaluation of average VM utilization achieved by MCHC-TO and existing task orchestration methods under different workload levels.
In contrast, the proposed MCHC-TO maintains a stable average VM utilization across all load levels, indicating effective resource management and the avoidance of server overload. This behavior is enabled by continuously evaluating both VM capacity and server location for each incoming task, allowing the system to adapt its offloading decisions accordingly. When interpreted jointly with the service delay and failure rate results, this stable utilization pattern suggests a more effective distribution of workload across edge servers.
Overall, the results confirm the effectiveness of the proposed MCHC-TO framework in handling diverse workload levels, as it consistently achieves favorable performance in service time, task failure rate, and resource utilization relative to existing methods.
5. Conclusions and Future Directions
In this paper, we developed MCHC-TO, a task orchestrator based on a multi-criteria relational clustering approach for efficient task allocation in dynamic MEC environments. Given the complexity of evaluating multiple conflicting factors, MCHC-TO leveraged PROMETHEE-based ranking and hierarchical divisive clustering to identify the most suitable edge server for execution. The simulation results using EdgeCloudSim showed that MCHC-TO outperformed the existing approaches by reducing the average service latency, task failure rates, and edge server overload, thereby enhancing system performance under varying workloads. To the best of our knowledge, this is the first task orchestration model in MEC to employ multi-criteria clustering based on PROMETHEE net flow scores.
This study focuses on two primary evaluation criteria: server location and capacity. However, real-world MEC environments are influenced by a broader range of factors. In future works, we will extend the decision model to include additional criteria, such as MD density per ES, uplink/downlink bandwidth availability, and instantaneous server queue length. Incorporating these factors will improve congestion management and enable more accurate representation of network and resource dynamics. In addition, future work will investigate WAN-aware orchestration strategies to further reduce cloud transmission failures under peak load. In particular, we plan to explore collaborative edge execution, where partitionable or resource-intensive tasks are divided into subtasks and processed cooperatively across neighbouring edge servers when a single node lacks sufficient capacity. Such cooperative processing can retain more workload within the edge layer, reduce reliance on cloud offloading, and mitigate WAN congestion effects. Finally, we intend to incorporate Stochastic Multi-Criteria Acceptability Analysis (SMAA) method to address the uncertainty in criteria weights and preference thresholds, further enhancing decision robustness under dynamic MEC conditions.
Author Contributions
Conceptualization, M.A., A.S.A. and A.C.; methodology, M.A., A.S.A. and A.C.; software, M.A.; formal analysis, M.A., A.S.A. and A.C.; investigation, M.A., A.S.A. and A.C.; data curation, M.A.; writing—original draft preparation, M.A.; writing—review and editing, M.A., A.S.A. and A.C.; visualization, M.A.; supervision, A.S.A. and A.C.; project administration, A.S.A. All authors have read and agreed to the published version of the manuscript.
Funding
The project was funded by KAU Endowment (WAQF) at King Abdulaziz University, Jeddah, Saudi Arabia. The authors, therefore, acknowledge with thanks WAQF and the Deanship of Scientific Research (DSR) for technical and financial support.
Data Availability Statement
This study is based on simulation experiments conducted using the EdgeCloudSim platform. The datasets generated consist of large-scale log files and scenario-dependent outputs and are not publicly archived due to their size and configuration-specific nature. Representative data samples and experiment configurations can be made available from the corresponding author upon reasonable request.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| MEC | Mobile Edge Computing |
| MD | Mobile Device |
| ES | Edge Server |
| MCDM | Multi-Criteria Decision Making |
| CRITIC | Criteria Importance Through Intercriteria Correlation |
| PROMETHEE | Preference Ranking Organization Method for Enrichment Evaluation |
| DHC | Divisive Hierarchical Clustering |
| AHC | Agglomerative Hierarchical Clustering |
| DRL | Deep Reinforcement Learning |
References
- Mahapatra, A.; Mishra, K.; Pradhan, R.; Majhi, S.K. Next generation task offloading techniques in evolving computing paradigms: Comparative analysis, current challenges, and future research perspectives. Arch. Comput. Methods Eng. 2024, 31, 1405–1474. [Google Scholar] [CrossRef] [Scilit]
- Abdulazeez, D.H.; Askar, S.K. Offloading Mechanisms Based on Reinforcement Learning and Deep Learning Algorithms in the Fog Computing Environment. IEEE Access 2023, 11, 12555–12586. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Z.; Li, H.; Tang, Z.; Gu, D.; Zhang, J. A Clustering Offloading Decision Method for Edge Computing Tasks Based on Deep Reinforcement Learning. New Gener. Comput. 2023, 41, 85–108. [Google Scholar] [CrossRef] [Scilit]
- Ishizaka, A.; Lokman, B.; Tasiou, M. A stochastic multi-criteria divisive hierarchical clustering algorithm. Omega 2021, 103, 102370. [Google Scholar] [CrossRef] [Scilit]
- Fang, J.; Hu, J.; Wei, J.; Liu, T.; Wang, B. An efficient resource allocation strategy for edge-computing based environmental monitoring system. Sensors 2020, 20, 6125. [Google Scholar] [CrossRef] [Scilit]
- Yadav, S.; Mohan, R.; Yadav, P.K. Task Allocation Model for Optimal System Cost Using Fuzzy C-Means Clustering Technique in Distributed System. Ing. Des Syst. D’Information 2020, 25, 59–68. [Google Scholar] [CrossRef] [Scilit]
- Yadav, S.; Narang, K.; Singh, A. Task allocation for optimal system cost using hierarchical clustering in distributed system. In Proceedings of the AIP Conference Proceedings; AIP Publishing LLC: Melville, NY, USA, 2024; Volume 3087, p. 180001. [Google Scholar]
- Jamil, S.U.; Khan, M.A.; Rehman, S.U. Resource allocation and task off-loading for 6G enabled smart edge environments. IEEE Access 2022, 10, 93542–93563. [Google Scholar] [CrossRef] [Scilit]
- Liu, X.; Yu, J.; Wang, J.; Gao, Y. Resource allocation with edge computing in IoT networks via machine learning. IEEE Internet Things J. 2020, 7, 3415–3426. [Google Scholar] [CrossRef] [Scilit]
- Li, W.; Chen, J.; Li, Y.; Wen, Z.; Peng, J.; Wu, X. Mobile edge server deployment towards task offloading in mobile edge computing: A clustering approach. Mob. Netw. Appl. 2022, 27, 1476–1489. [Google Scholar] [CrossRef] [Scilit]
- Liu, Y.; Yan, J.; Zhao, X. Deep-reinforcement-learning-based optimal transmission policies for opportunistic UAV-aided wireless sensor network. IEEE Internet Things J. 2022, 9, 13823–13836. [Google Scholar] [CrossRef] [Scilit]
- Qin, L.; Lu, H.; Lu, Y.; Zhang, C.; Wu, F. Joint Optimization of Base Station Clustering and Service Caching in User-Centric MEC. IEEE Trans. Mob. Comput. 2023, 23, 6455–6469. [Google Scholar] [CrossRef] [Scilit]
- Hao, Y.; Cao, J.; Wang, Q.; Du, J. Energy-aware scheduling in edge computing with a clustering method. Future Gener. Comput. Syst. 2021, 117, 259–272. [Google Scholar] [CrossRef] [Scilit]
- Thakkar, J.J. Multi-Criteria Decision Making; Springer: Berlin/Heidelberg, Germany, 2021; Volume 336. [Google Scholar]
- Sonmez, C.; Ozgovde, A.; Ersoy, C. Fuzzy Workload Orchestration for Edge Computing. IEEE Trans. Netw. Serv. Manag. 2019, 16, 769–782. [Google Scholar] [CrossRef] [Scilit]
- Jamil, M.N.; Hossain, M.S.; Islam, R.U.; Andersson, K. Workload Orchestration in Multi-Access Edge Computing Using Belief Rule-Based Approach. IEEE Access 2023, 11, 118002–118023. [Google Scholar] [CrossRef] [Scilit]
- Sonmez, C.; Tunca, C.; Ozgovde, A.; Ersoy, C. Machine Learning-Based Workload Orchestrator for Vehicular Edge Computing. IEEE Trans. Intell. Transp. Syst. 2021, 22, 2239–2251. [Google Scholar] [CrossRef] [Scilit]
- Yamansavascilar, B.; Baktir, A.C.; Sonmez, C.; Ozgovde, A.; Ersoy, C. DeepEdge: A Deep Reinforcement Learning Based Task Orchestrator for Edge Computing. IEEE Trans. Netw. Sci. Eng. 2023, 10, 538–552. [Google Scholar] [CrossRef] [Scilit]
- Alfakih, T.; Hassan, M.M.; Gumaei, A.; Savaglio, C.; Fortino, G. Task offloading and resource allocation for mobile edge computing by deep reinforcement learning based on SARSA. IEEE Access 2020, 8, 54074–54084. [Google Scholar] [CrossRef] [Scilit]
- Wu, H.; Geng, J.; Bai, X.; Jin, S. Deep reinforcement learning-based online task offloading in mobile edge computing networks. Inf. Sci. 2024, 654, 119849. [Google Scholar] [CrossRef] [Scilit]
- Zheng, T.; Wan, J.; Zhang, J.; Jiang, C. Deep reinforcement learning-based workload scheduling for edge computing. J. Cloud Comput. 2022, 11, 3. [Google Scholar] [CrossRef] [Scilit]
- Hsieh, L.T.; Liu, H.; Guo, Y.; Gazda, R. Deep reinforcement learning-based task assignment for cooperative mobile edge computing. IEEE Trans. Mob. Comput. 2023, 23, 3156–3171. [Google Scholar] [CrossRef] [Scilit]
- Liu, Q.; Yang, J.; Yan, Z. Dynamic resource orchestration in edge computing environments using multi-agent reinforcement learning. Knowl. Inf. Syst. 2025, 67, 9363–9383. [Google Scholar] [CrossRef] [Scilit]
- Shooshtarian, L.; Lan, D.; Taherkordi, A. A clustering-based approach to efficient resource allocation in fog computing. In Proceedings of the Pervasive Systems, Algorithms and Networks: 16th International Symposium, I-SPAN 2019, Naples, Italy, 16–20 September 2019; pp. 207–224. [Google Scholar]
- Ros, F.; Riad, R.; Guillaume, S. Deep clustering framework review using multicriteria evaluation. Knowl.-Based Syst. 2024, 285, 111315. [Google Scholar] [CrossRef] [Scilit]
- De Smet, Y.; Guzmán, L.M. Towards multicriteria clustering: An extension of the k-means algorithm. Eur. J. Oper. Res. 2004, 158, 390–398. [Google Scholar] [CrossRef] [Scilit]
- De Smet, Y. An extension of PROMETHEE to divisive hierarchical multicriteria clustering. In Proceedings of the 2014 IEEE International Conference on Industrial Engineering and Engineering Management; IEEE: New York, NY, USA, 2014; pp. 555–558. [Google Scholar]
- Huang, L.; Feng, X.; Feng, A.; Huang, Y.; Qian, L.P. Distributed deep learning-based offloading for mobile edge computing networks. Mob. Netw. Appl. 2018, 27, 1123–1130. [Google Scholar] [CrossRef] [Scilit]
- Behzadian, M.; Kazemzadeh, R.B.; Albadvi, A.; Aghdasi, M. PROMETHEE: A comprehensive literature review on methodologies and applications. Eur. J. Oper. Res. 2010, 200, 198–215. [Google Scholar] [CrossRef] [Scilit]
- Brans, J.P.; De Smet, Y. PROMETHEE Methods. In Multiple Criteria Decision Analysis: State of the Art Surveys; Greco, S., Ehrgott, M., Figueira, J.R., Eds.; Springer: New York, NY, USA, 2016; pp. 187–219. [Google Scholar] [CrossRef] [Scilit]
- Taherdoost, H.; Madanchian, M. Using PROMETHEE method for multi-criteria decision making: Applications and procedures. Iris J. Econ. Bus. Manag. 2023, 1. [Google Scholar] [CrossRef] [Scilit]
- Krishnan, A.R.; Kasim, M.M.; Hamid, R.; Ghazali, M.F. A modified CRITIC method to estimate the objective weights of decision criteria. Symmetry 2021, 13, 973. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Q.; Fan, J.; Gao, C. CRITID: Enhancing CRITIC with advanced independence testing for robust multi-criteria decision-making. Sci. Rep. 2024, 14, 25094. [Google Scholar] [CrossRef] [Scilit]
- Giordani, P.; Ferraro, M.B.; Martella, F. Introduction to Clustering; Springer: Singapore, 2020. [Google Scholar]
- Sonmez, C.; Ozgovde, A.; Ersoy, C. EdgeCloudSim: An environment for performance evaluation of Edge Computing systems. In Proceedings of the 2017 Second International Conference on Fog and Mobile Edge Computing (FMEC); IEEE: New York, NY, USA, 2017; pp. 39–44. [Google Scholar] [CrossRef] [Scilit]
- Alghamdi, M.; Alam, A.; Nallanathan, A.; Cherif, A. Dynamic Clustering-based Task Orchestrator in Mobile Edge Computing. In Proceedings of the 2024 International Wireless Communications and Mobile Computing (IWCMC); IEEE: New York, NY, USA, 2024; pp. 1613–1618. [Google Scholar]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.