1. Introduction
As a fundamental research task in the field of remote sensing (RS) image understanding and intelligent interpretation, RS image scene classification aims to automatically categorize input images into corresponding scene classes based on the spatial configurations of ground objects, texture distribution patterns, semantic contextual relations, and overall regional structures. Driven by the rapid advancements in high-resolution satellites, aerial photography platforms, and unmanned aerial vehicle (UAV) systems, modern RS data exhibit a clear trend toward higher spatial resolution, wider coverage, denser observation frequencies, and increasingly complex scene content. Consequently, the automatic, accurate, and efficient extraction of scene semantic information from massive RS imagery has become an indispensable technical foundation for numerous applications, such as land-use and land-cover (LULC) mapping, urban functional zone identification, ecological environmental assessment, disaster risk analysis, and military situational awareness [
1,
2,
3].
Early remote sensing scene classification methods primarily relied on hand-crafted visual features, such as color histograms, texture descriptors, Scale-Invariant Feature Transform (SIFT) [
4], Local Binary Patterns (LBP) [
5], histogram of oriented gradients (HOG) [
6], and bag-of-visual-words (BoVW) models [
7]. While these approaches demonstrate certain effectiveness on specific datasets and simple scenes, their feature representations are typically limited to low-level visual attributes. Consequently, they struggle to adequately characterize the complex multi-object compositional relationships, scale variations, and high-level semantic structures inherent in high-resolution remote sensing scenes. In recent years, the rapid development of deep convolutional neural networks (CNNs) has significantly propelled research in remote sensing image scene classification. Deep networks represented by AlexNet, VGGNet, GoogLeNet, ResNet, and DenseNet can automatically learn hierarchical representations—ranging from edges and textures to local objects and global scene semantics—through multilayer nonlinear mappings [
8,
9,
10,
11]. These models have achieved performance significantly superior to traditional methods across multiple benchmark datasets. Building upon this foundation, researchers have further incorporated techniques such as multi-scale feature fusion, attention mechanisms, context modeling, local region matching, graph structure reasoning, knowledge distillation strategy and Vision Transformers [
12,
13,
14,
15,
16]. These advancements aim to enhance the models’ representational capability for the complex spatial structures and long-range dependencies within remote sensing images. However, deep learning models typically rely heavily on large-scale annotated samples for training. Annotating remote sensing images is not only highly costly but also strictly requires specialized geospatial knowledge and expert interpretation experience. For new regions, novel categories, or time-sensitive emergency tasks, obtaining sufficient annotated samples is often impractical. Therefore, achieving reliable recognition of remote sensing scene categories under the condition of limited annotated samples has emerged as one of the most urgent core challenges in the intelligent interpretation of remote sensing data.
Few-shot learning aims to achieve rapid generalization to novel categories using only a few labeled samples. Its core idea is to construct a task distribution from a large set of base categories, enabling the model to learn transferable discriminative knowledge across tasks during training, and then perform classification on new tasks with only a few support samples during testing [
17,
18,
19,
20]. In recent years, few-shot learning has been widely introduced into the field of remote sensing scene classification, giving rise to the important research direction of few-shot remote sensing scene classification. Compared with natural images, remote sensing scenes exhibit more prominent issues of intra-class variation and inter-class similarity. On one hand, the same category can present significant differences under different geographic regions, seasons, imaging angles, spatial resolutions, and sensor conditions. For example, farmland shows markedly different texture patterns depending on the season and crop type, while man-made scenes such as airports, harbors, and industrial areas also exhibit large visual variations due to differences in spatial scale and functional layout. On the other hand, different categories often share similar land cover components and texture patterns, for instance, highways versus runways, commercial areas versus dense residential areas, rivers versus coastlines, and forests versus wetlands—all exhibit strong visual similarities. Under few-shot conditions, the limited support samples cannot adequately cover the intra-class distribution, leading to problems such as biased class prototype estimation, unstable embedding space distribution, and blurred classification boundaries for query samples.
Existing few-shot remote sensing scene classification methods can generally be categorized into metric learning-based, meta-learning-based, feature enhancement-based, and graph relational modeling-based approaches. Metric learning methods typically learn an embedding space and perform classification based on the distance or similarity between support and query samples, with representative examples including Siamese Networks, Matching Networks, Prototypical Networks, and Relation Networks [
17,
18,
19,
20]. Meta-learning methods, by contrast, aim to optimize model initialization or learn task adaptation strategies so that the model can adapt to novel categories after only a few gradient updates [
21]. Methods tailored for remote sensing scenarios further incorporate local region descriptors, attention mechanisms, class prototype rectification, graph relational inference, and hierarchical semantic modeling to alleviate the classification difficulties caused by the complexity of remote sensing imagery [
22,
23,
24,
25,
26,
27]. Although these methods have substantially advanced the performance of few-shot remote sensing scene classification, most of them still conduct embedding learning and similarity measurement primarily in a Euclidean feature space. In general, sample representations are obtained through global average pooling, vector concatenation, or linear projection, and classification is then performed using Euclidean distance, cosine distance, or learnable similarity functions. To some extent, this modeling paradigm overlooks the underlying higher-order statistical structures and non-Euclidean geometric properties inherent in remote sensing scene features.
In fact, remote sensing scenes are typically composed of multiple land-cover objects, texture patterns, and spatial structures [
28]. Their deep convolutional features not only encode channel-wise response intensities but also contain higher-order correlations across different spatial locations, feature channels, and local regions. If convolutional feature maps are simply compressed into Euclidean vectors, critical spatial arrangement information and second-order statistical dependencies may be lost. In recent years, symmetric positive definite (SPD) matrices and their associated Riemannian manifolds have attracted extensive attention in fields such as pattern recognition, computer vision, electroencephalogram signal analysis, and image classification [
29,
30]. SPD matrices can naturally characterize the covariance structure, second-order statistical information, and multivariate correlations of sample features. However, the space of SPD matrices is not a linear Euclidean space but a Riemannian manifold with intrinsic curvature. Ignoring its geometric structure and directly applying Euclidean operations may destroy the positive definiteness of the matrices as well as their intrinsic distance relationships. In contrast, performing metric learning, feature transformation, and mean estimation on the Riemannian manifold enables a more faithful characterization of the geometric relationships among SPD samples [
31,
32]. Therefore, integrating deep convolutional features with Riemannian manifold learning provides a new research avenue for addressing higher-order correlation modeling and stable class prototype estimation in few-shot remote sensing scene classification.
Based on the above analysis, this paper proposes a few-shot remote sensing scene classification method that integrates a zigzag scanning feature sequence with a Riemannian geometric barycenter network. The core idea of this method is as follows: First, the deep convolutional feature maps of remote sensing images are extracted using ResNet12, retaining Euclidean feature representations with local spatial semantics. Second, the two-dimensional feature maps are converted into one-dimensional feature sequences with spatial order constraints via zigzag scanning so that the feature sequences preserve as much two-dimensional local adjacency and structural continuity as possible during the flattening process. Third, an autoregressive moving average (ARMA) model is employed to model the dynamic dependencies of the serialized features, and an SPD matrix is constructed based on its state-dependent structure, thereby embedding the sample representation from Euclidean space into a Riemannian manifold space. Fourth, manifold feature extraction is performed through SPD network layers such as bilinear mapping and eigenvalue rectification. Finally, a Riemannian geometric barycenter network is designed to estimate the class geometric barycenter in the SPD manifold, and the class prototypes are optimized through intra-class compactness and inter-class separability constraints, thereby enhancing discriminability and generalization capability under few-shot conditions. The main contributions of this paper are summarized as follows.
(1) A Riemannian manifold feature embedding (RMFEmb) layer is proposed by combining zigzag scanning, ARMA sequence modeling, and SPD manifold embedding. It encodes higher-order statistical dependencies into symmetric positive definite matrices and embeds them onto the Riemannian manifold while preserving geometric structure.
(2) A Riemannian manifold feature extraction (RMFExt) layer is developed, which performs a Bilinear Mapping (BiMap) to preserve geodesic distances, followed by a Rectified Eigenvalues (ReEig) operation to extract principal components directly on the Riemannian manifold. This layer captures non-Euclidean geometric properties beyond conventional Euclidean methods.
(3) A Riemannian geometric barycenter (RieGB) layer is designed to compute task-level and class-level barycenters on the SPD manifold. It jointly optimizes intra-class compactness and inter-class margins, alleviating unstable prototypes and ambiguous decision boundaries under few-shot conditions.
The rest of the paper is organized as follows: the related work is briefly introduced in
Section 2, which includes remote sensing image scene classification, image classification based on Riemannian manifold space, and few-Shot remote sensing image scene classification. In
Section 3, we introduce the proposed method.
Section 4 presents the experiment results. We present a discussion in
Section 5, and we draw a conclusion in
Section 6.
3. Methodology
3.1. Overall Architecture of the Proposed Method
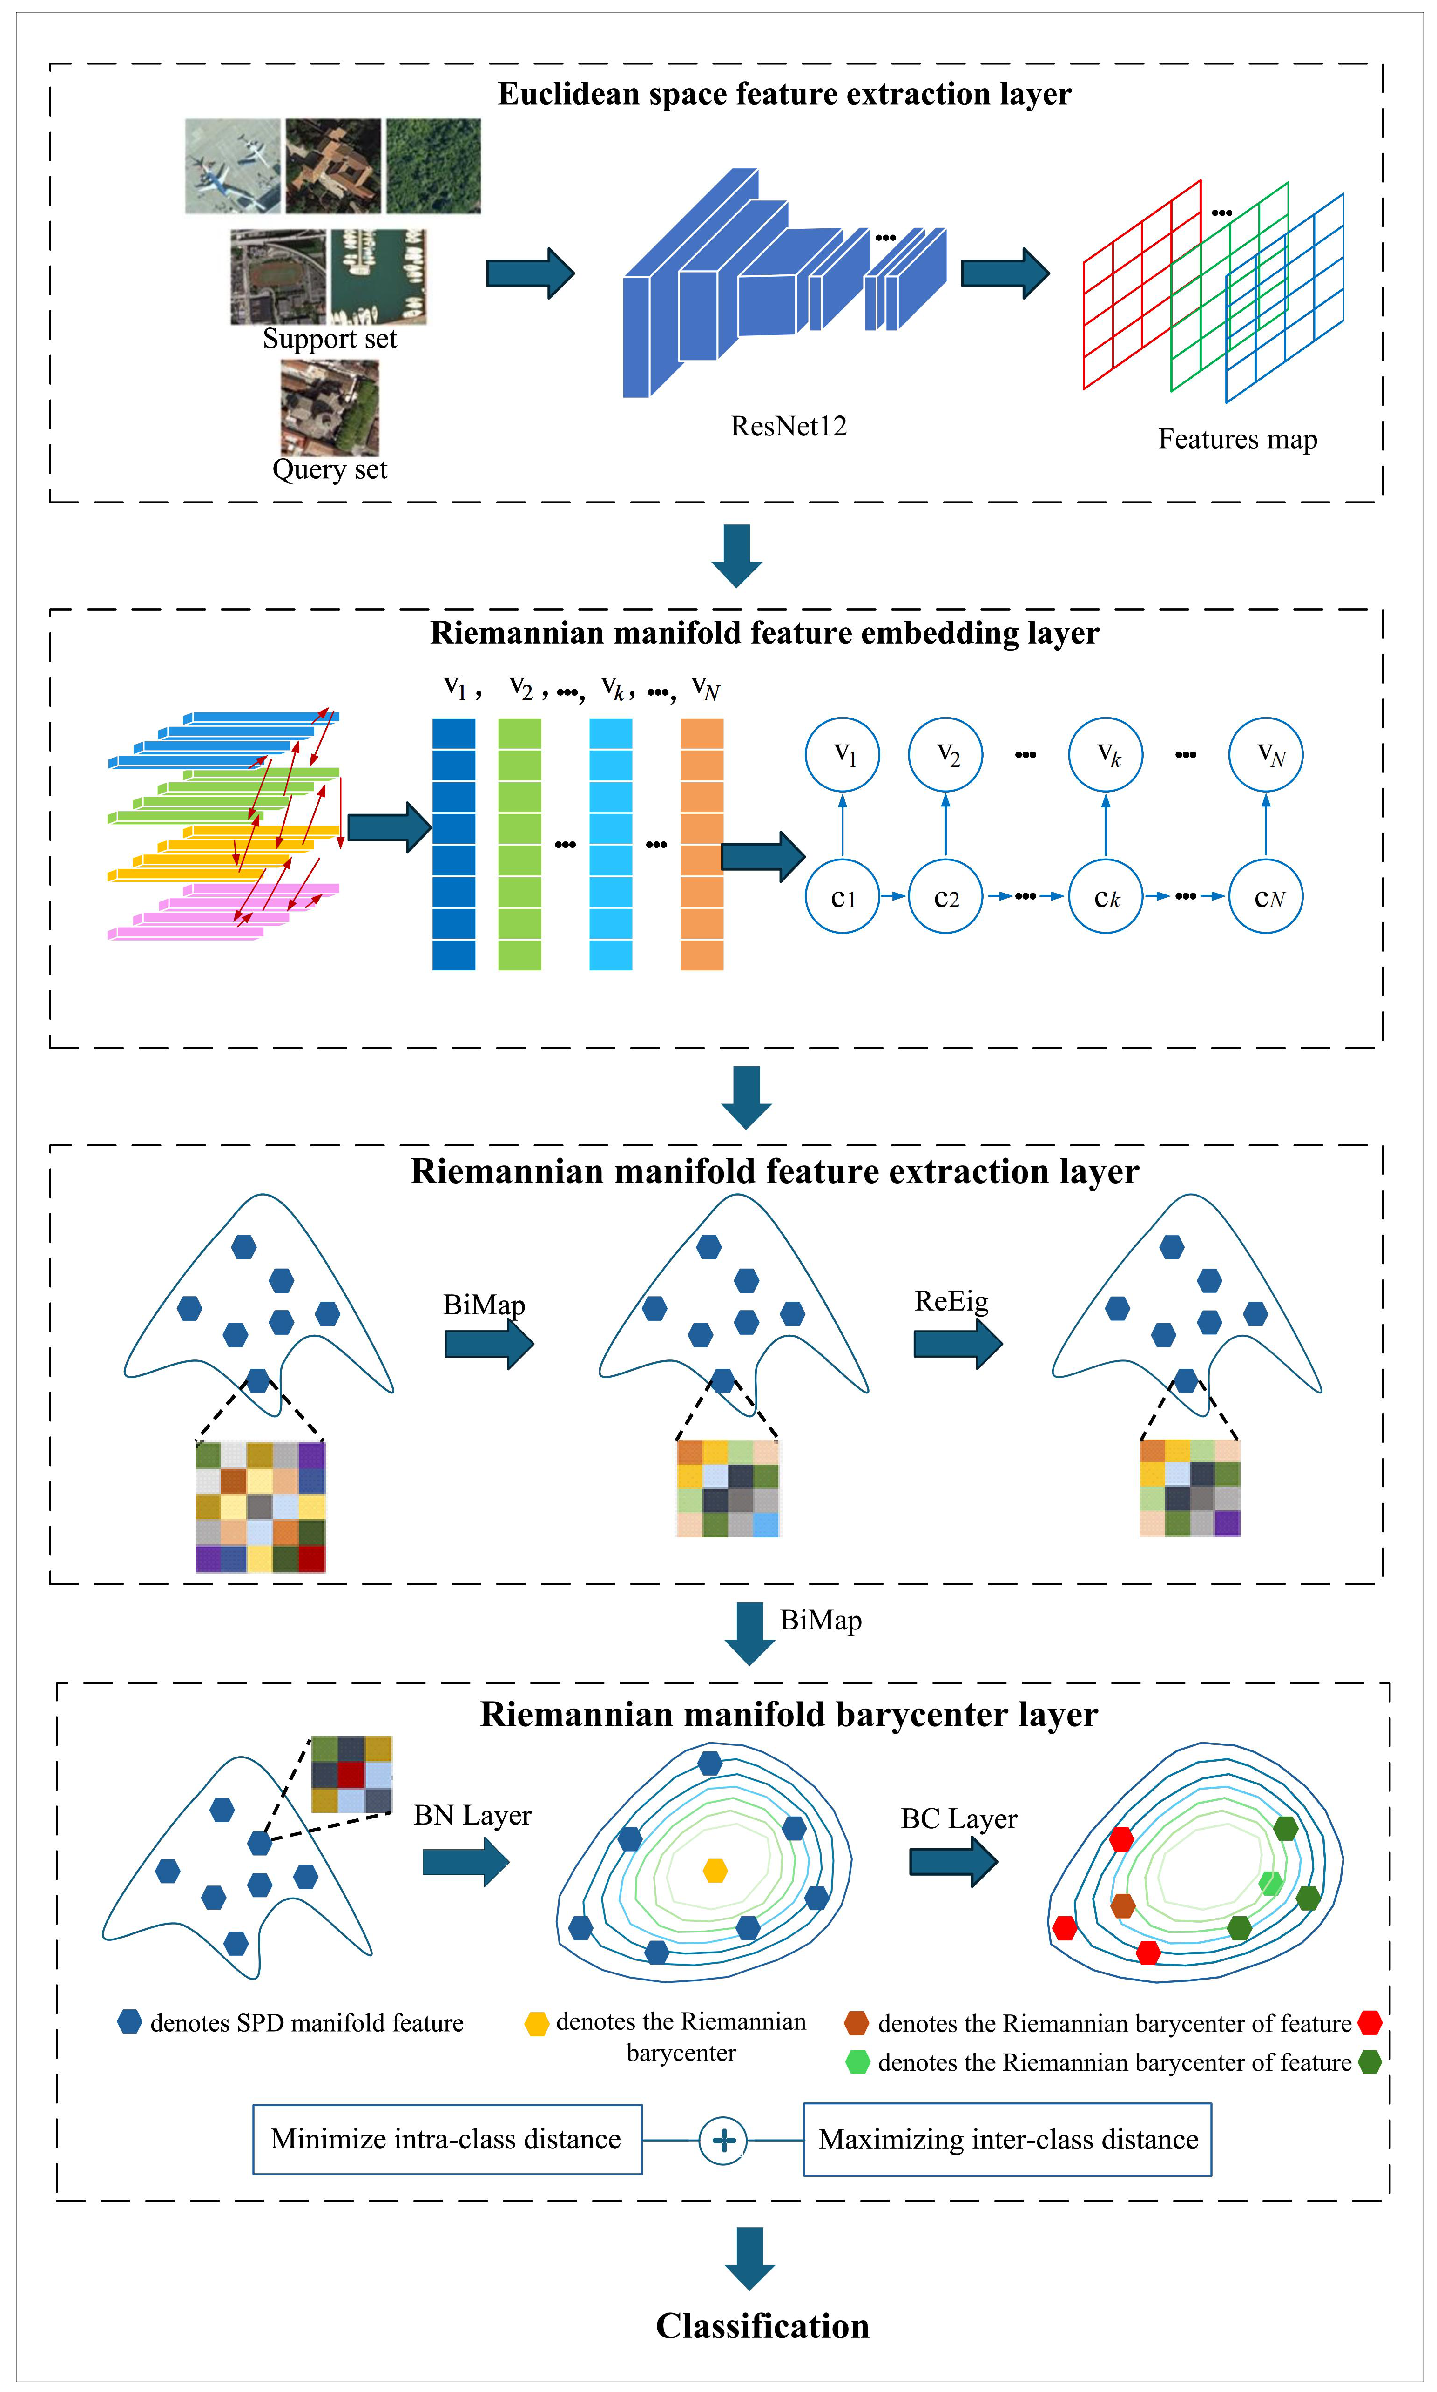
The overall architecture of the ZSFS-RGBN method proposed in this paper is illustrated in
Figure 1. The method mainly consists of four core components: a Euclidean space feature extraction layer, a Riemannian manifold feature embedding layer, a Riemannian manifold feature extraction layer, and a Riemannian geometric barycenter network layer. Specifically, remote sensing images are first fed into a pre-trained ResNet12 backbone network for deep feature extraction, outputting a feature tensor of size
, where
H and
W denote the height and width of the feature map, respectively, and
C denotes the number of channels. Subsequently, the feature map of each channel is reorganized into a one-dimensional sequence via zigzag scanning, effectively preserving the spatial correlation and energy concentration characteristics among pixels. On this basis, an autoregressive moving average (ARMA) model is constructed to capture the spatiotemporal dependencies in the sequence. After obtaining the model parameters, they are mapped onto a Grassmann manifold to achieve feature embedding in a non-Euclidean geometric space. Furthermore, the points on the Grassmann manifold are mapped onto a symmetric positive definite (SPD) manifold, and the SPDNet network is employed for deep Riemannian manifold feature extraction. Finally, a Riemannian geometric barycenter network is designed to compute the Riemannian barycenter of samples from each class, and a joint supervised loss function is constructed to achieve joint optimization of intra-class compactness and inter-class separability. The entire model is trained in an end-to-end manner, enabling the collaborative optimization of feature learning and metric learning through the joint loss function.
3.2. Euclidean Space Feature Extraction
In the Euclidean space feature extraction stage, this paper adopts ResNet12 as the backbone network for deep feature extraction from input remote sensing images. ResNet12 is a lightweight variant of the ResNet family, specifically designed for few-shot learning tasks, maintaining strong feature representation capability while controlling network parameters and computational complexity [
10]. The core design concepts of ResNet12 include a residual learning mechanism, batch normalization technology, and a global average pooling strategy. The residual learning mechanism solves the problems of gradient vanishing and network degradation in deep network training by introducing skip connections. In traditional CNNs, as the number of layers increases, theoretically stronger feature representation capability should be achieved, but due to gradient attenuation during backpropagation, the training error of deep networks may actually be higher than that of shallow networks. Residual networks form an identity mapping path by directly bypassing one or more convolutional layers and adding the input to the output, transforming the learning objective from directly learning the desired mapping
to learning the residual mapping
. When the optimal mapping is close to the identity mapping, the residual mapping is optimized to be near zero, which is easier to optimize than directly learning the identity mapping. The specific structure of a residual block can be expressed as:
where
x and
y denote the input and output tensors of the residual block, respectively,
represents the residual mapping to be learned, typically consisting of two or three convolutional layers followed by batch normalization and ReLU activation functions. The residual connection allows gradients to propagate directly along the identity path to shallow layers, effectively alleviating the gradient vanishing problem and enabling stable training of deeper networks.
The specific network structure of ResNet12 is as follows: first, a convolutional layer with 64 output channels and stride 1, followed by batch normalization and ReLU activation. Subsequently, four residual blocks (ResBlocks) are used, each containing two convolutional layers, each followed by batch normalization and ReLU activation. The output channels of the four residual blocks are 64, 128, 256, and 512, respectively. After each residual block, if the number of channels changes, a convolution is used for skip connection dimension matching. After the fourth residual block, global average pooling compresses the spatial dimension of each feature map to , obtaining a 512-dimensional feature vector. For few-shot learning tasks, ResNet12 typically does not connect a fully connected classification layer after global average pooling but directly outputs feature vectors for use in downstream metric learning modules. Compared with deeper networks such as ResNet34 or ResNet50, ResNet12 has fewer parameters and faster inference speed, making it more suitable for rapid adaptation in few-shot scenarios. The feature extraction process of ResNet12 can be formalized as: given an input image , after passing through the feature extraction network , a feature map is obtained, where H and W depend on the downsampling factor in the network. In the ResNet12 configuration adopted in this paper, after four residual blocks with stride-2 downsampling, and . This feature map retains sufficient spatial resolution for subsequent zigzag scanning serialization operations while containing rich semantic information.
3.3. Riemannian Manifold Feature Embedding
3.3.1. Zigzag Feature Sequence
After obtaining the 2D feature map from ResNet12, how to effectively organize and represent these features becomes a key issue in few-shot remote sensing scene classification. Traditional global average pooling averages features across all spatial positions to obtain a C-dimensional global feature vector, which significantly reduces dimensionality but completely loses spatial structural information. Traditional row-wise or column-wise flattening preserves information from all spatial positions but destroys local adjacency relationships among features and is sensitive to image rotation and flipping. To address these issues, this paper introduces a zigzag scanning strategy to serialize the 2D feature maps into 1D feature sequences.
Zigzag scanning was originally applied in the field of image compression, particularly in encoding discrete cosine transform coefficients in the JPEG standard. Its basic idea is to traverse matrix elements along diagonal directions in an alternating pattern, starting from the top-left corner, moving in a diagonal direction, changing direction upon reaching boundaries, until all elements are traversed. This scanning method has two advantages: first, zigzag scanning maintains spatial locality, with adjacent elements in the original feature map remaining adjacent or close in the scanned sequence; second, zigzag scanning is relatively robust to geometric transformations such as rotation and flipping, because the geometric properties of the scanning path align with the statistical characteristics of natural images.
For the feature map
F, zigzag scanning is performed independently on each channel. Let the feature map of the
c-th channel be
.
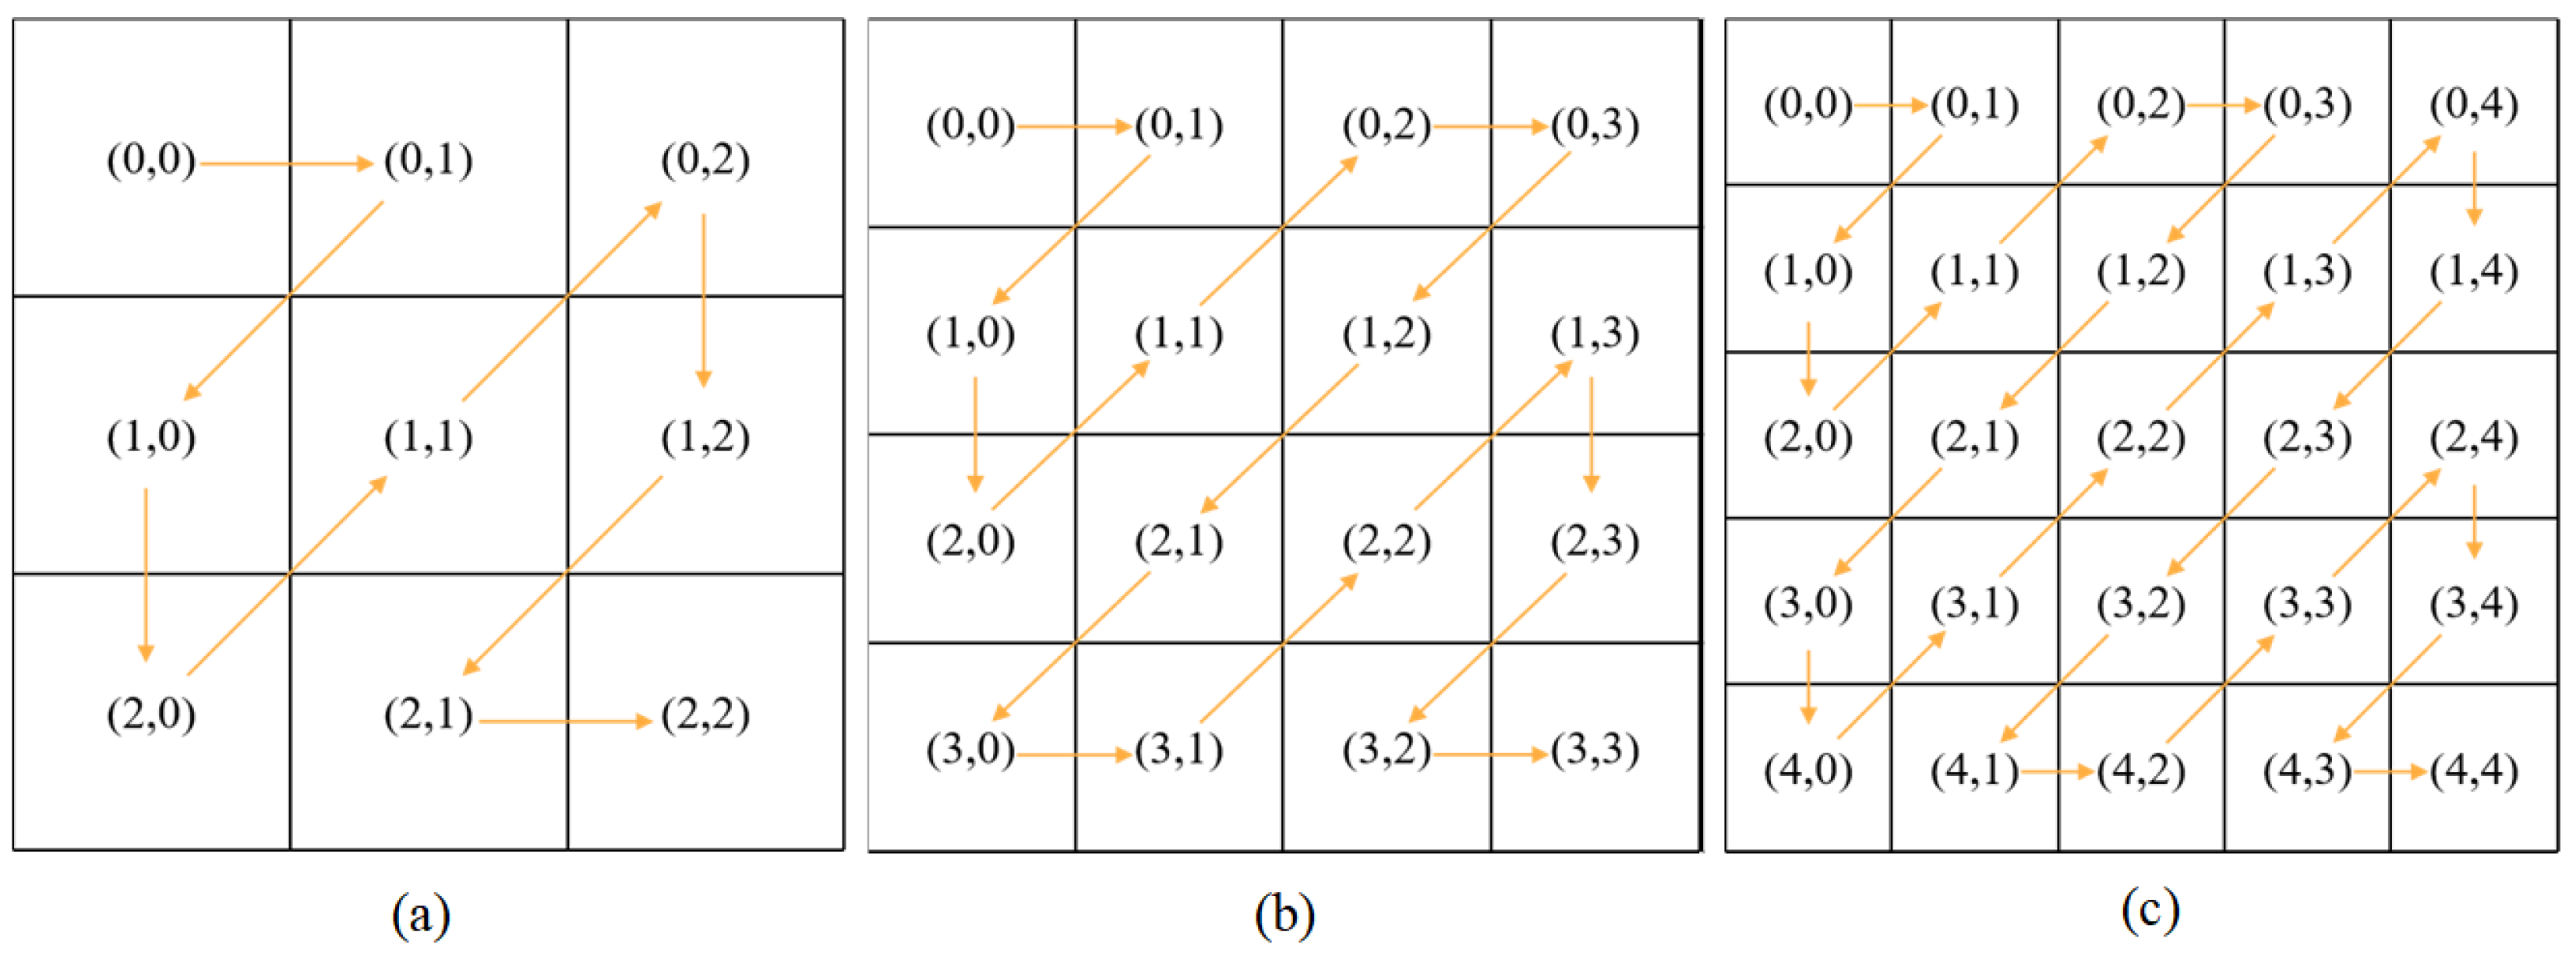
Figure 2 shows the zigzag scanning strategies of feature maps with different sizes. Taking the
feature map (
Figure 2b) as an example, the zigzag scanning path follows the order:
The general traversal rules are defined as follows, starting from the top-left corner with an initial horizontal direction, and alternating diagonal traversal upon hitting matrix boundaries. For a square matrix with , the zigzag scanning path can be formally described as:
Initialization: Start at (r = 0, c = 0), first move right to (0,1). When moving in the down-left diagonal direction: If − 1 bottom boundary, move right to (r, c + 1), switch to up-right direction; If c = 0 (left boundary), move down to (r + 1, c), switch to up-right direction; Otherwise, move to (r + 1, c − 1), keep down-left direction. When moving in the up-right diagonal direction: If − 1 (right boundary), move down to (r + 1, c), switch to down-left direction; If r = 0 (top boundary), move right to (r, c + 1), switch to down-left direction; Otherwise, move to (r − 1, c + 1), keep up-right direction.
Following these rules, the traversal alternates between down-left and up-right diagonal passes, moving right or down at the matrix boundaries to start the next diagonal pass. After traversing all positions, a one-dimensional sequence is obtained. Concatenating the zigzag sequences of all C channels along the channel dimension yields the final feature sequence , where is the sequence length, and is the vector of feature values at the t-th position in zigzag order across all channels. This feature sequence V serves as the input data for subsequent ARMA modeling. The advantage of zigzag scanning over row-wise and column-wise scanning is: row-wise scanning first scans the first row from left to right, then the second row, etc., which maintains locality within rows but causes jumps when switching between rows; column-wise scanning similarly suffers from jumps between columns; while zigzag scanning traverses along diagonal directions, keeping spatially adjacent points adjacent in the sequence, better matching the spatial correlation structure of natural images.
3.3.2. Autoregressive Moving Average Model
After obtaining the zigzag feature sequence , it is necessary to further model the dependency relationships among feature vectors in the sequence to capture the spatial structural patterns of remote sensing images. Traditional sequence modeling methods such as recurrent neural networks or Transformers are powerful but require large amounts of training data and have high computational complexity, making them unsuitable for few-shot scenarios. This paper employs the autoregressive moving average (ARMA) model to model the feature sequence, which has low parameterization and good statistical interpretability, and its parameters can be naturally mapped to Riemannian manifolds.
The ARMA model is a classical time series analysis method that expresses the current observation as a linear combination of historical observations plus a linear combination of historical noises. In this paper, the zigzag sequence
V is treated as a multivariate time series, where each time step
t corresponds to a spatial position on the zigzag path, and the observation vector
is the feature value of all channels at that position. To capture spatial dependencies in the sequence, this paper adopts a state-space form of the ARMA model, whose core idea is to introduce a low-dimensional state variable to capture the core dynamic characteristics of the sequence. The state-space ARMA model consists of an observation equation and a state transition equation, expressed as:
where
is the state vector at time
t,
d is the state dimension, typically much smaller than the observation dimension
C, used to extract the core dependencies of the sequence.
is the observation matrix, mapping the low-dimensional state vector to the high-dimensional observation space.
is the state transition matrix, characterizing the dynamic evolution of the state over time and reflecting the spatial dependency relationships between adjacent feature vectors in the zigzag sequence.
is the zero-mean Gaussian observation noise, with
as the covariance matrix, corresponding to noise interference in the feature extraction process.
is the zero-mean Gaussian state noise, with
as the covariance matrix, corresponding to uncertainty in state changes.
Estimating the ARMA model parameters
is a critical issue under few-shot conditions. Since the state variable
is an unobservable latent variable, direct maximum likelihood estimation is complex. This paper adopts an estimation method based on singular value decomposition (SVD), which has high computational efficiency and numerical stability. First, to avoid redundant representation of the state space, an orthogonality constraint
is imposed on the observation matrix, where
is the
d-order identity matrix. This constraint ensures the uniqueness of the state space basis and simplifies parameter solving. Then, singular value decomposition is performed on the zigzag feature sequence matrix
:
where
is the matrix of left singular vectors (columns orthogonal),
is a diagonal matrix with singular values on the diagonal,
is the matrix of right singular vectors (columns orthogonal), and
is the rank of the matrix. According to the orthogonality constraint, the estimate of the observation matrix takes the first
d left singular vectors, i.e.,
, because the left singular vectors already contain the core semantic information of the feature sequence and satisfy the orthogonality condition. The estimate of the state vector sequence is
, where each column of
corresponds to the state vector
at a given time.
The state transition matrix
B must satisfy
and is solved using the least squares method with the pseudoinverse:
where
denotes the matrix pseudoinverse. When
, the pseudoinverse exists and is unique; when the sequence length
T is small, the pseudoinverse still provides a stable minimum-norm solution. The state noise is
, and its covariance matrix is estimated as:
The observation noise is
, and its covariance matrix is estimated as:
Thus, the zigzag feature sequence of each sample is represented by the ARMA model parameters . These parameters capture the dynamic evolution patterns of the feature sequence, reflecting the spatial dependency characteristics of land cover structures in remote sensing images. However, directly using these parameters as feature vectors ignores the non-Euclidean topological structure of the parameter space, so they need to be further mapped to a Riemannian manifold.
3.4. Riemannian Manifold Feature Extraction
The ARMA model parameters constitute a dynamic description of the zigzag feature sequence, but these parameters lie in spaces with specific geometric structures, and directly applying Euclidean methods would lose important geometric information. Specifically, the observation matrix satisfies the orthogonality constraint , and the d-dimensional subspace spanned by its column vectors corresponds to a point on the Grassmann manifold . The state transition matrix lies in the matrix space , and the state noise covariance lies on the symmetric positive definite matrix manifold . To fully exploit these geometric structures, this paper first maps the ARMA parameters to the Grassmann manifold and then adopts the SPDNet architecture for deeper Riemannian manifold feature extraction.
The core idea of mapping ARMA parameters to the Grassmann manifold is to construct an extended observation matrix that incorporates the dynamic information of state transitions into the subspace representation. Specifically, the extended observation matrix is defined as:
where
L is the length of the zigzag sequence, and
denotes the observation matrix after
l steps of state transition. Each row of the extended observation matrix
O corresponds to an observation after a specific order of state transition, and the subspace
spanned by its row vectors fuses dynamic information from multiple time scales. QR decomposition is performed on
O to obtain an orthonormal basis matrix
(satisfying
), and the subspace corresponding to this basis matrix is the point
g on the Grassmann manifold
. This mapping process encodes the dynamic characteristics of the ARMA model as geometric points on the Grassmann manifold, enabling similarity between different samples to be measured by geodesic distances on the manifold.
After obtaining the Grassmann manifold representation, this paper uses a Riemannian manifold feature extraction network based on the SPDNet architecture to further process these representations. SPDNet is a deep neural network specifically designed for handling symmetric positive definite matrix data and is capable of performing nonlinear transformations and feature learning while preserving SPD structure. First, the Grassmann manifold points need to be converted into SPD matrix representations. Given the orthonormal basis matrix , construct the SPD matrix , which is a rank-L positive semidefinite matrix. By adding a regularization term , it becomes strictly positive definite: , where is a small positive number. Thus, each sample is represented as an SPD matrix on the symmetric positive definite matrix manifold.
The core structure of SPDNet includes BiMap layers and ReEig layers. Let the input of the
l-th layer be the SPD matrix
. The operation of a BiMap layer is defined as:
where
is a column full-rank transformation matrix (
), and its row number
determines the dimension of the output SPD matrix. To ensure that the output remains an SPD matrix,
must satisfy the full-rank condition. The BiMap layer functions similarly to a fully connected or convolutional layer in a CNN, projecting high-dimensional SPD matrices to low-dimensional SPD spaces through bilinear transformation while preserving the manifold structure. This operation can be understood as a coordinate transformation on the manifold, recombining original features into more discriminative representations. The transformation matrix
is a learnable parameter of the network, optimized through backpropagation.
The ReEig layer (rectified eigenvalues layer) is analogous to the ReLU activation function in CNNs and performs a nonlinear transformation on the eigenvalues of SPD matrices to enhance feature discriminability. The ReEig layer is defined as:
where
is the eigenvalue decomposition of the input SPD matrix,
is a diagonal matrix with eigenvalues on the diagonal,
is a preset threshold parameter, and
takes the element-wise maximum, i.e.,
. This operation raises all eigenvalues smaller than
to
, preventing numerical instability due to excessively small eigenvalues while introducing nonlinear activation capability. Through the ReEig layer, the network can learn more discriminative feature representations, suppressing noise and redundant information. After stacking multiple BiMap and ReEig layers, the features are input into the Riemannian geometric barycenter network for classification.
3.5. Riemannian Geometric Barycenter Network
To further enhance the discriminative power of deep features, this paper designs a Riemannian geometric barycenter network (RGBN). The core idea of this network is to cluster features of the same class on the Riemannian manifold while separating features of different classes. The RGBN consists of two submodules: the barycentric normalization layer and the barycentric classification layer.
The barycentric normalization layer aims to align and stabilize the SPD features within a batch. Since Riemannian distances follow a right-skewed distribution, direct computation of the barycenter can be unstable due to outliers, and feature distributions may vary across different batches. Let the SPD features in a mini-batch be
, where
is the batch size. First, compute the Riemannian barycenter (geometric mean)
of these features, defined as the point minimizing the weighted sum of squared distances:
where
is the affine-invariant Riemannian distance, defined as:
is the eigenvalues of the matrix
. The Riemannian barycenter can be computed iteratively using the Karcher flow algorithm: first project all SPD features to the tangent space at
via the logarithmic map, compute the arithmetic mean in the tangent space, and then map back to the manifold via the exponential map, repeating until convergence.
The process of aligning each feature
to the barycenter
involves three steps. First, project
to the tangent space at the barycenter using the logarithmic map:
Second, perform parallel transport of
in the tangent space, moving the tangent vector from the tangent space at
to the tangent space at a reference point
. Parallel transport is defined as:
Finally, map the tangent vector back to the manifold using the exponential map, obtaining the normalized SPD feature:
After barycentric normalization, the SPD features within the batch are aligned to a common reference point, reducing distributional differences and the influence of outliers.
The goal of the barycentric classification layer is to simultaneously minimize intra-class distances and maximize inter-class distances. Let the normalized features be
with corresponding labels
, where
is the number of classes. For each class
c, a learnable Riemannian barycenter
is maintained, initialized as the Riemannian barycenter of the support samples of that class and updated during training via gradient descent. The intra-class compactness loss encourages features of the same class to approach their class barycenter:
The inter-class separation loss increases the distance differences between features of different classes and their barycenters. Inspired by the Z-score concept in statistical testing, a loss term based on distance distribution normalization is designed:
where
is the Riemannian distance between sample
and the barycenter
of class
j,
and
are the running mean and standard deviation of
in the current batch, and
is the classification logits obtained by passing
through the LogEig layer and a fully connected layer. The first term measures the deviation of samples from non-class barycenters using standardized distances, increasing the penalty when a sample falls within the distance distribution of other classes; the second term is the standard cross-entropy loss, ensuring basic classification capability.
To ensure the numerical stability of the logarithmic term
in
, we use an exponential moving average to update
during training:
where
is the batch-wise estimate at the
t-th iteration and
is the momentum coefficient. Before evaluating the logarithm,
is clamped into a valid numerical range:
where
. The logarithmic term is therefore computed as
. This prevents the input of the logarithm from becoming zero or extremely small. The derivative of this term is:
Since , the gradient is bounded by , avoiding infinite gradients. Moreover, exponential moving average smoothing and gradient clipping further suppress abrupt gradient oscillations, ensuring stable end-to-end optimization.
The proposed ZSFS-RGBN method adopts an end-to-end joint training strategy, with the total loss function composed of several complementary loss terms that jointly optimize the quality of feature representations and classification performance. The design of the total loss function follows three principles: feature discriminability, classification accuracy, and geometric constraint integrity. Feature discriminability requires compact intra-class features and separated inter-class features; classification accuracy requires the model to correctly predict sample categories; geometric constraint integrity requires that operations on the manifold maintain the closure of the SPD structure.
The complete form of the total loss function is:
where
is the intra-class compactness loss,
is the inter-class separation loss,
is a hyperparameter balancing the loss terms. Through this end-to-end joint optimization, ZSFS-RGBN learns deep feature representations with intra-class compactness and inter-class separability, significantly improving the performance of remote sensing scene classification under few-shot conditions.
4. Experiments and Analysis
4.1. Datasets Description
To evaluate the performance and robustness of the proposed framework, we conducted experiments on three widely recognized remote sensing image scene classification benchmarks: NWPU-RESISC45 (NWPU) [
2], UC-Merced (UC) [
7], and WHU-RS19 (WHU) [
58]. In order to maintain a rigorous evaluation with prior research, we adopted a category-based splitting strategy for the training (
), validation (
), and testing (
) sets. The detailed distribution of scene categories across these three subsets is documented in
Table 1.
The NWPU dataset, released by Northwestern Polytechnical University, stands as one of the most comprehensive and challenging benchmarks in the field. It comprises 31,500 remote sensing images categorized into 45 distinct scene classes, with 700 images per class. Each image features a spatial resolution of pixels. Due to its large scale and high intraclass variation, it provides a rigorous test for the generalization capabilities of our model. In our experiments, 25 categories were allocated for training, 10 for validation, and the remaining 10 for testing.
The UC dataset is a classic benchmark for land-use scene recognition, which contains 2100 high-resolution images across 21 land-use categories. Each category consists of 100 images with a pixel size of
. The images were originally derived from the USGS National Map Urban Area Imagery collection. For this study, the 21 categories were split into 10 for training, 5 for validation, and 6 for testing, following the distribution specified in
Table 1.
The WHU dataset is provided by Wuhan University; this dataset is composed of 950 high-resolution images ( pixels) extracted from Google Earth. It encompasses 19 scene categories, with 50 images per category. Despite its relatively small total volume, the dataset is characterized by significant variations in scale, illumination, and orientation, making it an ideal choice for testing model sensitivity to environmental changes. We divided the 19 categories into 9 for training, 5 for validation, and 5 for testing.
4.2. Experiment Setup
All experiments in this paper are implemented under the PyTorch 2.2.2 deep learning framework and run on a hardware platform configured with an NVIDIA RTX 2080Ti GPU to ensure efficient training and inference. To maintain input consistency and reduce the impact of resolution differences on feature extraction, all remote sensing images from the three datasets are uniformly resized to a fixed resolution of pixels before being fed into the network. During the training phase, a series of effective data augmentation strategies are applied to improve the generalization ability of the model and alleviate overfitting under limited samples, which include random horizontal flipping, random center cropping, and random grayscale transformation. In accordance with the standard evaluation paradigm of few-shot learning, this paper adopts an episode-based meta-training mechanism for model optimization. Specifically, 2000 episodes are randomly constructed for the training stage, 500 episodes for the validation stage, and another 2000 independent episodes for the final testing stage to ensure statistical reliability. Each episode strictly follows the 5-way K-shot setting ( for 1-shot and for 5-shot). In each episode, 5 distinct categories are first sampled from the corresponding dataset split, then K labeled images per category are selected as the support set for prototype learning, and 15 unlabeled images per category are used as the query set for performance evaluation. To quantitatively evaluate the classification performance of the proposed method and all comparison approaches, the average classification accuracy (CA) over 2000 testing episodes with a confidence interval is utilized as the primary evaluation metric. For model optimization, the Stochastic Gradient Descent (SGD) optimizer is employed to update all network parameters, and the initial learning rate is set to to ensure stable convergence and effective gradient propagation.
4.3. Analysis of Experiment Results
To comprehensively evaluate the effectiveness of our proposed ZSFS-RGBN method, we compared it with various state-of-the-art (SOTA) few-shot learning methods across three public remote sensing datasets: NWPU-RESISC45 (NWPU), UC-Merced (UC), and WHU-RS19 (WHU). The evaluation was conducted under the standard 5-way 1-shot and 5-way 5-shot classification settings. The quantitative results are presented in
Table 2,
Table 3 and
Table 4.
As shown in
Table 2, the NWPU dataset is highly challenging due to its large scale and severe intraclass variations. Despite these challenges, our proposed ZSFS-RGBN method achieves the highest classification accuracies of 84.59% and 92.19% in the 5-way 1-shot and 5-way 5-shot settings, respectively. Compared to the second-best performing method, DiffPR-Net, our approach yields significant performance gains of 2.74% in the 1-shot scenario and 2.78% in the 5-shot scenario. Furthermore, compared to classic meta-learning approaches such as MAML and RelationNet (RN), the improvements are remarkably substantial (e.g., over 35% higher than MAML in 1-shot). This demonstrates that the ZSFS-RGBN framework is highly capable of extracting discriminative and robust features even when data is extremely scarce and scene complexity is high.
Table 3 reports the comparative results on the UC dataset. While this dataset has fewer categories and images, it remains a standard benchmark for land-use classification. The proposed ZSFS-RGBN method once again consistently outperforms all other compared methods, achieving 63.22% for 5-way 1-shot and 82.61% for 5-way 5-shot tasks. Notably, in the 5-shot setting, our method surpasses the highly competitive DBA-RMCL model by a notable margin of 3.88%. This indicates that our model can effectively leverage slightly increased support samples to construct a much more accurate class representation, proving its strong adaptability to standard land-use scenarios.
The WHU dataset is characterized by variations in illumination, scale, and shooting angles.
Table 4 illustrates that our ZSFS-RGBN model exhibits exceptional robustness to these environmental changes. It achieves a superior accuracy of 89.14% in the 1-shot setting, exceeding the second-best DBA-RMCL (87.33%) by 1.81%. In the 5-shot setting, our method reaches an impressive accuracy of 98.69%, outperforming the strong baseline ICSFF (97.56%) by 1.13%. The ability to achieve near-perfect classification in the 5-shot scenario confirms that the proposed method effectively mitigates the negative impacts of multi-scale and illumination variations inherent in high-resolution remote sensing imagery.
Across all three datasets, a consistent trend can be observed: the performance in the 5-way 5-shot setting is uniformly better than that in the 5-way 1-shot setting for all methods. This is intuitive as providing five support samples per class rather than one significantly enriches the reference information, thereby reducing the risk of overfitting and improving the reliability of the prototype or feature matching. Most importantly, the proposed ZSFS-RGBN method maintains its leading position across datasets of varying scales and complexities. Whether dealing with the massive 45-category NWPU dataset or the highly variable WHU dataset, our model demonstrates superior generalization capability and stability, verifying the effectiveness of the core algorithmic design in ZSFS-RGBN for few-shot remote sensing scene classification.
4.4. Ablation Studies
To systematically evaluate the contribution of each core component in the proposed ZSFS-RGBN framework, we conduct comprehensive ablation experiments on the NWPU, UC, and WHU datasets under both 5-way 1-shot and 5-way 5-shot settings. The three key components under investigation are RMFEmb, RMFExt, and RieGB. RMFEmb includes zigzag scanning, ARMA modeling, and mapping to the Grassmann/SPD manifold. Removing it replaces the entire manifold embedding with simple channel-wise flattening and direct Euclidean feature vectors. RMFExt consists of the BiMap and ReEig layers that perform structure-preserving transformations on the SPD manifold. Removing RMFExt bypasses these layers, feeding the embedded SPD matrices directly into the barycenter layer. RieGB includes the barycentric normalization and barycentric classification layers with intra-class compactness and inter-class separation losses. Removing it replaces the RieGB layer with a standard SPDNet classification head (LogEig layer followed by a fully connected layer with cross-entropy loss).
Based on these, we construct four model variants:
Baseline (w/o all): Removes all three components. The ResNet12 feature maps are globally average-pooled into Euclidean vectors, and classification is performed using standard Prototypical Networks with Euclidean distance.
+ RMFEmb: Adds the RMFEmb layer to the baseline, but without RMFExt and RieGB. Classification uses a single BiMap layer followed by LogEig and fully connected layers.
+ RMFEmb + RMFExt: Further adds the RMFExt component, but still without the RieGB layer.
ZSFS-RGBN (Full): Includes all three components (RMFEmb, RMFExt, RieGB) as described in
Section 3.
All methods use the same ResNet12 backbone, training episodes, and hyperparameters for a fair comparison. The experimental results are reported in
Table 5.
Based on the results in
Table 5, the progressive integration of our proposed modules demonstrates a clear and consistent performance boost over the Euclidean baseline. Introducing the RMFEmb module brings steady accuracy gains across all datasets. Under the 1-shot setting, it improves accuracy by 2.39% on NWPU, 1.87% on UC Merced, and 1.86% on WHU-RS19. Under the 5-shot setting, the gains reach 1.57% on NWPU, 4.02% on UC Merced, and 0.81% on WHU-RS19. This indicates that encoding feature maps into Riemannian manifolds successfully captures higher-order statistical and spatial information typically lost in standard global average pooling. Building upon RMFEmb, the addition of the RMFExt module further refines these geometric representations. On the NWPU dataset, accuracy increases by 2.57% under the 1-shot setting and 1.59% under the 5-shot setting. On UC Merced, the improvements are 0.87% under the 1-shot setting and 1.57% under the 5-shot setting. On WHU-RS19, gains reach 2.25% (1-shot) and 0.58% (5-shot). These results prove that performing structure-preserving transformations directly on the manifold effectively extracts more discriminative non-Euclidean features. Finally, integrating the RieGB layer completes the architecture and provides substantial performance leaps. Under the 1-shot setting, further improvements are 3.50% on NWPU, 1.27% on UC Merced, and 1.68% on WHU-RS19. Under the 5-shot setting, the gains are 3.17% on NWPU, 3.48% on UC Merced, and 2.68% on WHU-RS19. This highlights that computing the Riemannian barycenter accurately estimates stable class prototypes, sharpening decision boundaries and reducing prototype bias when multiple support samples are available.
The ablation study confirms that the RMFEmb, RMFExt, and RieGB components are indispensable and mutually reinforcing. Working in synergy, the complete ZSFS-RGBN framework achieves total absolute improvements over the baseline ranging from 4.01% (UC Merced, 1-shot) to 9.07% (UC Merced, 5-shot), with other settings improving by 5.79–8.46%. These significant gains thoroughly validate the superiority and necessity of our proposed Riemannian geometric framework for few-shot remote sensing image classification.
4.5. Hyperparameters Analysis
(1) Sensitivity analysis of balance factor
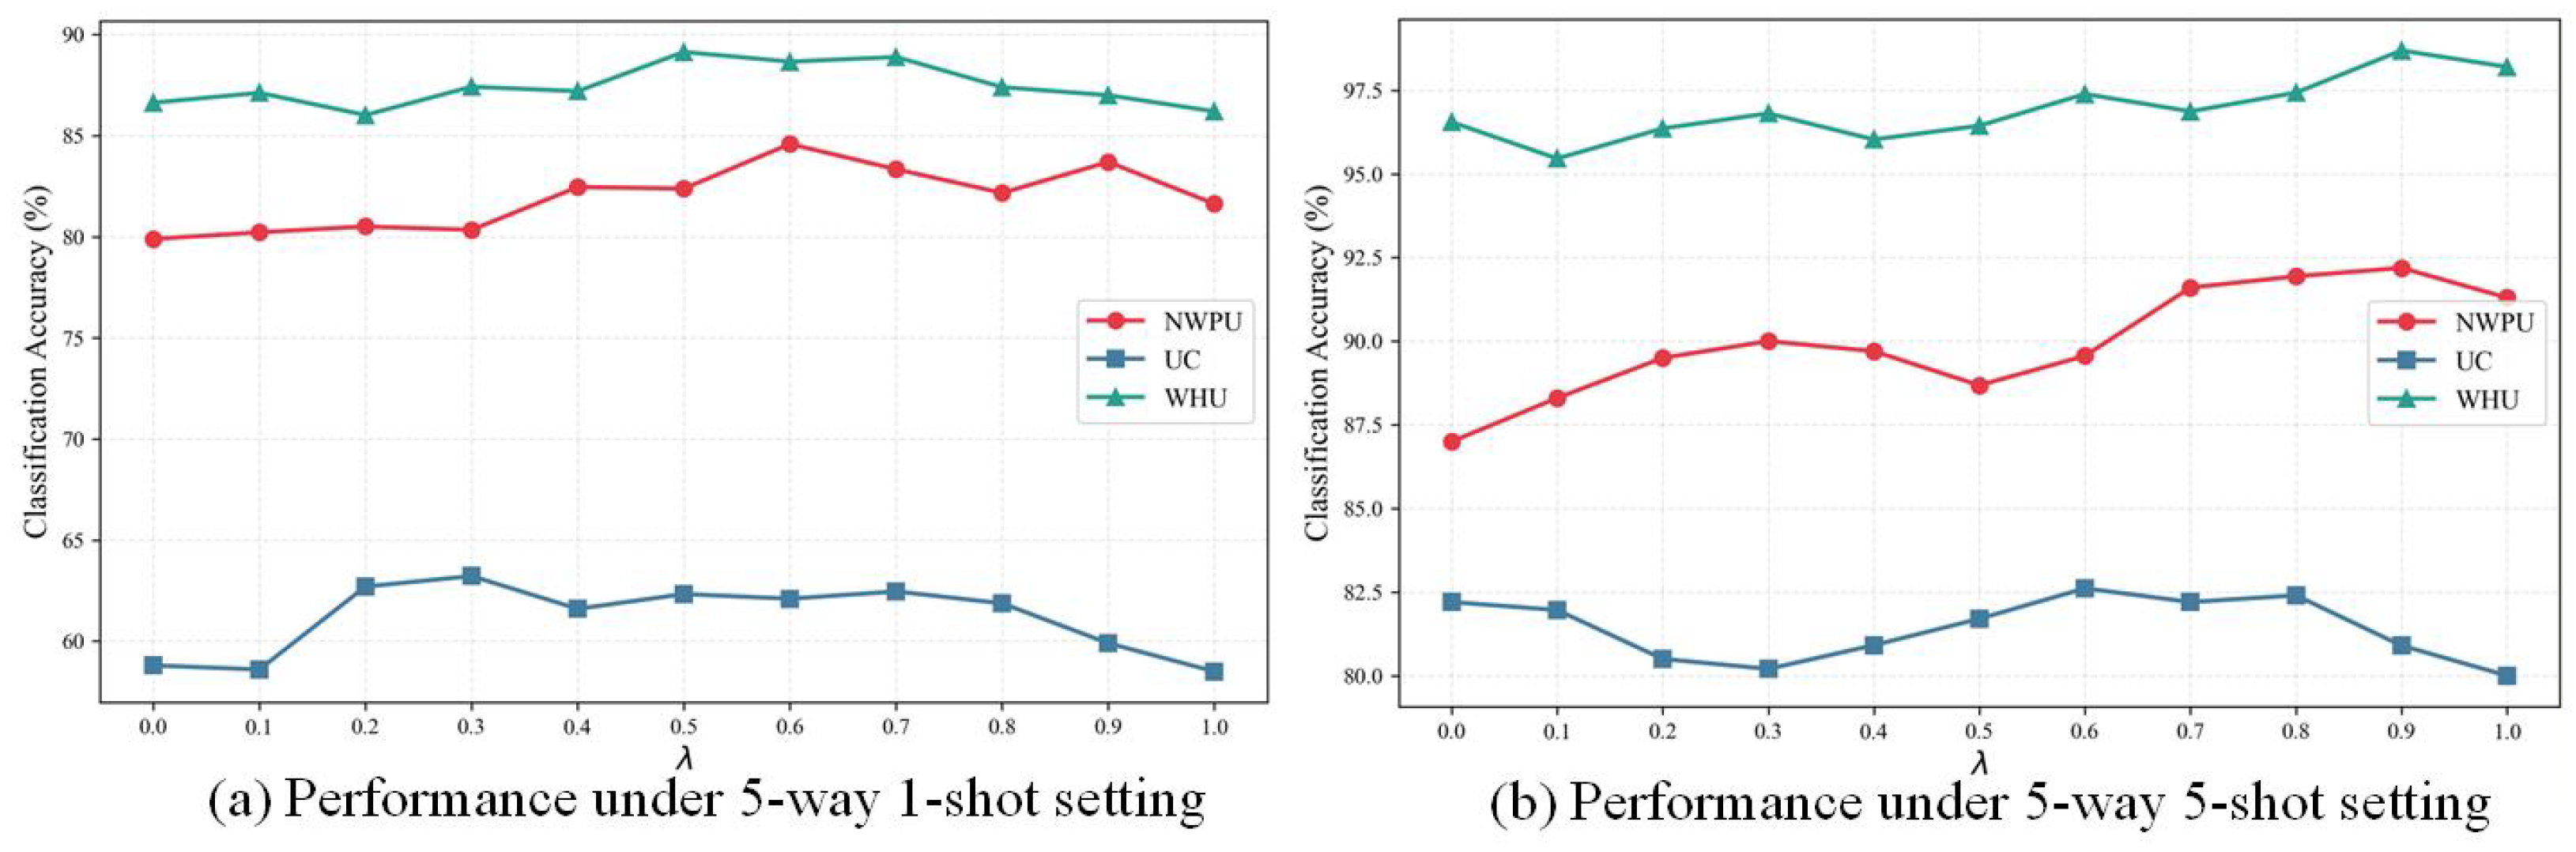
The balance factor in the joint loss function is a critical hyperparameter that regulates the relative importance between intra-class compactness loss and inter-class separability loss. To determine the optimal value of for few-shot remote sensing scene classification, we conducted exhaustive ablation experiments by varying from 0 to 1.0 at intervals of 0.1, covering all typical weighting ratios. All experiments were implemented on three benchmark datasets, namely NWPU, UC, and WHU, under two standard few-shot settings: 5-way 1-shot and 5-way 5-shot. All other experimental configurations and network parameters were kept strictly consistent to ensure fairness.
The quantitative classification results under different
values are visualized in
Figure 3. As observed from the experimental curves, the classification accuracy exhibits obvious fluctuations with the continuous adjustment of
, which is mainly attributed to the different sensitivities of each remote sensing dataset to the loss balance ratio under limited sample conditions. For the 5-way 1-shot setting, the optimal
values vary across datasets: the proposed model achieves the best performance when
on the NWPU dataset,
on the UC dataset, and
on the WHU dataset. For the 5-way 5-shot setting, the optimal values shift to 0.9 for NWPU, 0.6 for UC, and 0.9 for WHU. The overall results demonstrate that the classification performance is highly sensitive to the selection of
, and inappropriate values will weaken the feature discriminability by breaking the balance between intra-class aggregation and inter-class separation. The optimal
values obtained from comparative experiments are adopted in all subsequent formal experiments of the ZSFS-RGBN model, ensuring the stability and superiority of classification performance on diverse remote sensing datasets.
(2) Sensitivity analysis of zigzag sequence length
Table 6 reports the classification accuracies of the proposed ZSFS-RGBN with different zigzag sequence lengths
L on the three datasets under 5-way 1-shot and 5-way 5-shot settings. It can be observed that the model performance is sensitive to the choice of
L. As
L increases from 4 to 16, the accuracy generally improves on all three datasets, indicating that an appropriate zigzag sequence length helps preserve more effective spatial structure information for feature representation and classification. However, when
L is further increased to 25, the performance drops consistently, suggesting that excessively long sequences may introduce redundant information and weaken feature discriminability. Among all settings,
achieves the best results on NWPU, UC Merced, and WHU-RS19 under both 1-shot and 5-shot tasks, demonstrating that it provides a better balance between local detail preservation and global structural modeling. Therefore,
is adopted in all formal experiments.
4.6. Computation Efficiency Analysis
To evaluate the computational cost introduced by the proposed method while improving classification performance, we compare the proposed ZSFS-RGBN with several representative few-shot classification methods on the NWPU dataset under the 5-way 1-shot setting. Specifically, the number of parameters, FLOPs, training time, and inference time are reported, as shown in
Table 7. It can be observed that MN and PN have relatively simple architectures, with the same parameter size of 12.42 M and FLOPs of 516.2 G and 514.8 G, respectively, resulting in relatively low training and inference costs. Although RN enhances feature interaction capability, its parameter size increases substantially to 23.49 M, accompanied by higher computational complexity and runtime overhead. In contrast, ZSFS-RGBN contains only 12.60 M parameters, which is still much lower than that of RN, while its FLOPs, training time, and inference time reach 742.6 G, 3.06 s, and 0.548 s, respectively. This indicates that the additional cost of ZSFS-RGBN mainly arises from its more sophisticated feature representation and geometric modeling process, rather than from a significant increase in model size. According to
Table 2, under the same setting, ZSFS-RGBN achieves a classification accuracy of 84.59%, which is significantly higher than those of MN, PN, and RN. Overall, although ZSFS-RGBN introduces higher computational complexity and runtime cost, it yields substantial performance gains with a relatively well-controlled parameter size, demonstrating a favorable trade-off between accuracy and complexity.
4.7. Visualization Analysis
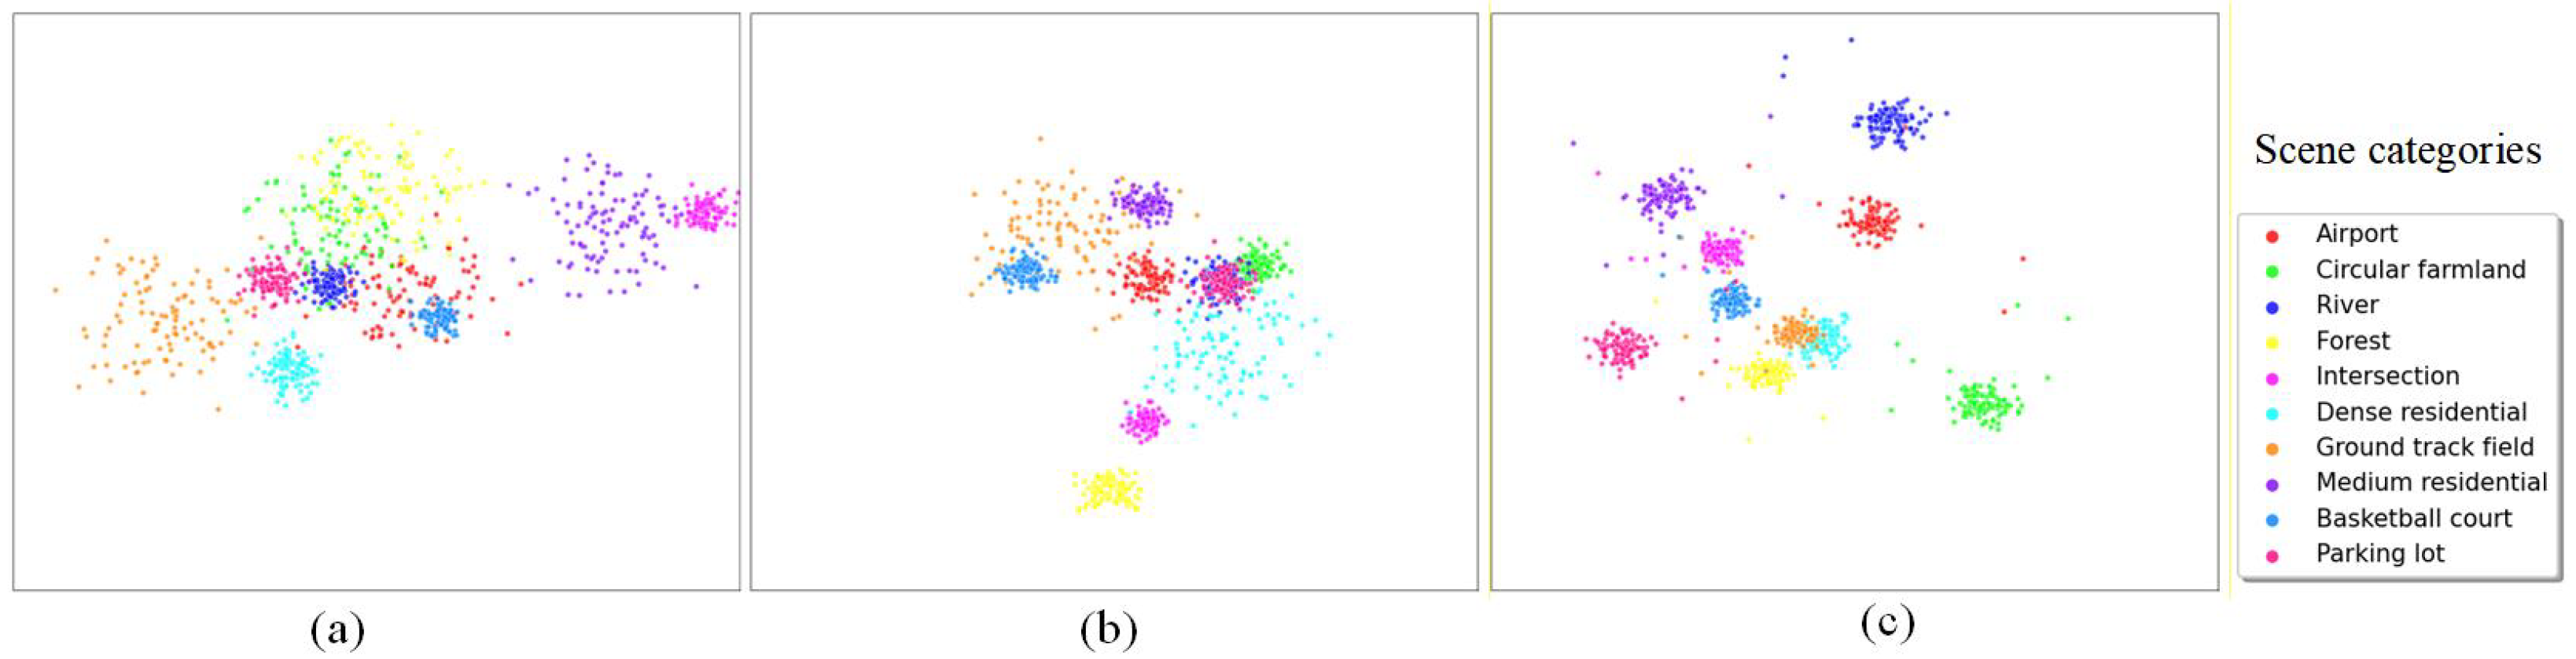
To intuitively demonstrate the discriminative capability of the proposed ZSFS-RGBN method in the few-shot remote sensing scene classification task, we employed t-SNE to project the deep features into a two-dimensional space for visualization. The experiments were conducted on the NWPU-RESISC45 dataset under the 5-way 5-shot setting. Specifically, we selected all 10 categories from the testing set and randomly sampled 100 images from each category for the comparative experiments by feature visualization. The visualization results are shown in
Figure 4.
Figure 4a shows the original image feature visualization, and
Figure 4b shows the features extracted from the baseline.
Figure 4c shows the features extracted from ZSFS-RGBN. From
Figure 4a, it can be observed that the original image features of different categories are severely mixed; this confirms that low-level pixel information alone is insufficient for distinguishing complex remote sensing scenes. In contrast,
Figure 4b shows that the baseline method, which relies on Euclidean space feature learning and global average pooling, achieves a certain degree of clustering. Remarkably,
Figure 4c demonstrates that the proposed ZSFS-RGBN method significantly improves feature discriminability. Features belonging to the same category are tightly clustered into compact clusters, and the inter-class margins are substantially enlarged. The t-SNE visualization thus provides strong evidence that ZSFS-RGBN is capable of learning highly discriminative feature representations under few-shot conditions.
5. Discussion
The experiment results presented in
Section 4 demonstrate that the proposed ZSFS-RGBN method consistently achieves superior performance over a wide range of state-of-the-art few-shot learning methods on three benchmark remote sensing scene datasets. In this section, we discuss the underlying reasons for these improvements, the implications of our findings, the limitations of the current work, and several promising directions for future research.
The success of ZSFS-RGBN can be attributed to three synergistic innovations that directly address the inherent challenges of few-shot remote sensing scene classification: large intra-class variation, high inter-class similarity, and loss of spatial structure in conventional Euclidean embeddings. First, the zigzag scanning strategy effectively preserves spatial locality and energy concentration. Unlike global average pooling, which discards all spatial information, or row-wise/column-wise flattening, which breaks diagonal continuity, zigzag scanning traverses feature maps along alternating diagonal directions. This maintains the adjacency of spatially close features in the resulting 1D sequence, which is crucial for capturing the anisotropic patterns frequently observed in remote sensing scenes. The t-SNE visualization in
Figure 4 confirms that the baseline method, which lacks this strategy, produces overlapping clusters, whereas ZSFS-RGBN yields well-separated and compact clusters. Second, the ARMA-based SPD embedding maps the feature sequence onto a Grassmann manifold, capturing second-order statistics and dynamic dependencies. Many remote sensing scenes are characterized not only by individual objects but also by the spatial arrangement and co-occurrence of textures. The ARMA model, through its state-space formulation, extracts latent spatial dynamics that reflect these structural relationships. By representing each sample as a point on a Riemannian manifold, the method naturally respects the non-Euclidean geometry features. This is a key departure from Euclidean metric learning, which treats all feature dimensions independently and linearly. The ablation study in
Table 5 shows that adding RMFEmb alone already brings clear gains, confirming the value of manifold embedding. Third, the RieGB jointly optimizes intra-class compactness and inter-class separation directly on the manifold. In few-shot scenarios, class prototypes estimated by simple averaging in Euclidean space are often biased due to the limited number of support samples. The RieGB layer computes the true Riemannian barycenter on the SPD manifold, which is a more robust and geometrically meaningful central tendency. The custom inter-class loss further pushes different class barycenters apart while pulling query samples toward their correct prototype. The ablation results indicate that RieGB provides the most substantial improvement in the 5-shot setting, where more support samples allow the barycenter to be estimated more reliably.
Our method outperforms recent strong baselines such as DiffPR-Net, ICSFF, DBA-RMCL, and ACL-Net across all three datasets. Notably, DiffPR-Net uses diffusion-based data augmentation to generate additional training samples, yet it still lags behind ZSFS-RGBN. This suggests that simply increasing the number of samples is not sufficient. Similarly, ACL-Net employs attention-based contrastive learning in Euclidean space, but it fails to capture the higher-order geometric structure that our Riemannian approach inherently provides.
Despite the strong performance of ZSFS-RGBN, two main limitations remain. First, the method assumes that the feature distributions of base and novel classes are similar, but in real applications, a large domain shift often exists (e.g., different sensors, geographic regions, or imaging conditions). The current Riemannian embedding does not explicitly model such domain discrepancies, which may degrade cross-domain few-shot transferability. Second, the method only processes single-modality optical images, whereas modern remote sensing platforms provide complementary data such as SAR, hyperspectral, and LiDAR. Fusing these heterogeneous modalities could offer richer information, but the current framework lacks a mechanism to integrate multi-modal SPD representations.
To overcome the above limitations, future research will focus on two directions. For cross-domain transferability, we plan to incorporate domain adaptation techniques directly into the Riemannian manifold, for instance by aligning class-specific SPD barycenters across domains via parallel transport or learning domain-invariant ARMA parameters through adversarial training. For multi-modal fusion, we will extend the framework to handle multiple modalities by constructing a joint SPD representation on a product manifold or learning a shared Riemannian space via bilinear fusion, enabling the model to exploit complementary information from different sensors and further boost few-shot classification accuracy in challenging real-world scenarios.




 ,