


Abstract
This study investigates exact algorithms for solving the Travelling Salesman Problem (TSP), formulated as the problem of finding a minimum Hamiltonian cycle in a complete weighted undirected graph. Two recursive algorithms are presented and analyzed. The first algorithm, denoted RecursiveHamiltonianCycle (RHC), performs an exhaustive recursive search of the solution space, while the second algorithm, denoted PrunedHamiltonianCycleSearch (PHCS), applies an early branch-pruning mechanism to eliminate non-promising partial solutions. The main objective of this research is to evaluate the influence of recursive branch pruning and initial upper-bound selection on the computational efficiency of exact TSP search procedures. A series of computational experiments was conducted using complete graphs containing between 12 and 21 vertices. The obtained results show that both algorithms always produce identical optimal Hamiltonian cycles. However, the PHCS algorithm requires significantly fewer recursive calls and substantially less execution time. Additional experiments demonstrate that the quality of the initial upper bound has a substantial impact on pruning efficiency. A nearest-neighbor heuristic was therefore used to generate high-quality initial solutions, resulting in further reductions in the search space. The results confirm that combining heuristic initialization with exact branch-pruning search significantly improves the practical applicability of exact TSP algorithms while preserving solution optimality.
1. Introduction
An essential component of every software system is the set of algorithms used for data processing and for implementing the required functionality. Their characteristics determine both the amount of main memory required to store the data structures in use and the execution time of the computational processes. Therefore, when developing algorithms, it is important to achieve a balance between the computational resources utilized and the performance attained. Research in the fields of algorithms and data structures has been actively evolving for decades, and comprehensive results and fundamental concepts have been presented in [1,2,3,4]. When designing an algorithm to solve a specific practical problem, one of the first tasks is the selection of an appropriate data structure. The way in which data are modeled and processed has a direct impact on the organization of the computational process and on the choice of the algorithmic approach, which may be recursive or iterative.
The question of choosing between a recursive and an iterative approach in algorithm development has been the subject of numerous studies. Study [5] presents research on the preferences of novice and experienced programmers when designing and implementing algorithms. The obtained results indicate an increasing interest in the use of recursive solutions in recent years. Reference [6] emphasizes that the choice between a recursive and an iterative approach should be determined by the characteristics of the specific problem being solved. In [7], a method for transforming recursive algorithms into iterative ones through the use of incremental computation techniques is proposed. The reported experimental results show that, in many cases, iterative implementations require more memory but execute faster. Various approaches for optimizing memory usage in recursive algorithms are discussed in [8]. Approaches for transforming iterative processes into recursive implementations are presented in [9]. Recursive and iterative implementations of algorithms are widely applied in various fields of science and practice, with representative examples presented in [10,11,12]. Despite the considerable number of existing studies, the choice between recursion and iteration remains an important scientific and practical issue, particularly in the development of algorithms for solving complex combinatorial optimization problems.
One class of problems for which the choice of an appropriate algorithmic approach is of crucial importance is the class of problems modeled using graph structures. For such problems, the efficiency of the employed algorithms has a direct impact on the execution time and on the ability to solve practical problems with large input datasets. In the present study, the problem of finding a minimum Hamiltonian cycle in a weighted graph has been selected as a test problem. This problem is known in the literature as the Travelling Salesman Problem (TSP) [1]. The problem provides a suitable environment for the analysis and comparison of different algorithmic implementations, since it belongs to the class of NP-hard combinatorial optimization problems [2].
Graph theory is one of the most intensively studied areas of discrete mathematics and computer science. Over the last decades, it has found widespread application in the modeling and analysis of a variety of real-world systems and processes [13]. A graph is a mathematical structure consisting of two sets of elements: a set of vertices and a set of edges. Formally, a graph can be represented by the ordered pair of sets (Vertices, Edges), where Vertices = {vertex1, vertex2, …, vertexk} is the set of vertices and Edges = {edge1, edge2, …, edgep} is the set of edges. In directed graphs, each edge is represented by an ordered pair of vertices (vertexi, vertexj), whereas in undirected graphs the order of the vertices is irrelevant. If a numerical value is assigned to each edge through a weight function c(i, j), the graph is called weighted. If c(i, j) = c(j, i), the graph is an undirected weighted graph. A sequence of vertices vertex1, vertex2, …, vertexq, in which every pair of consecutive vertices is connected by an edge, is called a path. A path whose starting and ending vertices coincide is called a cycle. A cycle that traverses each edge exactly once is called an Eulerian cycle, whereas a cycle that visits each vertex exactly once is called a Hamiltonian cycle. A graph is called complete if an edge exists between every pair of its vertices. Additional information on graph theory, graph data structures, and algorithms for solving various graph-related problems is presented in [13,14].
Graphs provide a convenient and effective framework for modeling, describing, and solving a wide range of practical problems. Numerous problems from science and practice, such as transportation problems, route planning problems, resource allocation problems, facility location problems, as well as problems related to timetable and schedule generation, can be successfully modeled using graph structures and solved with appropriate algorithms [13]. Some of these problems can be solved using linear optimization methods, whereas others require specialized algorithmic approaches. In many real-world applications, the size of the input data is considerable, which necessitates the use of efficient algorithms with acceptable execution times. In many cases, finding an exact solution requires a large number of computations, making the practical solution of the corresponding problem extremely difficult or even impossible within a reasonable amount of time [15]. For this reason, graph-based combinatorial optimization problems provide a suitable environment for the development, analysis, and comparison of algorithms with different characteristics in terms of accuracy and computational efficiency.
The number of real-world practical problems that can be modeled using graphs is extremely large. The present study considers the problem of finding a minimum Hamiltonian cycle in a complete, weighted, and undirected graph. This problem is a combinatorial optimization problem known in the literature as the Travelling Salesman Problem (TSP). A detailed description of the problem and its variants is presented in [16,17,18,19]. During the last decades, numerous algorithmic approaches for solving the TSP have been developed [20,21,22,23]. In general, these approaches can be divided into two main groups: exact and approximate methods. Exact algorithms guarantee the discovery of an optimal solution, but they are usually characterized by high computational costs and are applicable mainly to problems of limited size [19,24,25,26].
Existing exact approaches to the TSP include dynamic-programming methods, branch-and-bound algorithms, branch-and-cut procedures, and their numerous variations. These methods differ considerably in their computational complexity, implementation characteristics, and practical applicability. The objective of the present study is not to introduce a new state-of-the-art exact TSP solver or to compete with highly optimized implementations. Instead, the focus is placed on analyzing the influence of recursive branch pruning and heuristic upper-bound initialization within a recursive exact-search framework. The presented experiments are therefore intended to evaluate the contribution of these optimization strategies to the efficiency of the search process.
On the other hand, approximate algorithms find a solution in a considerably shorter time, but they do not guarantee its optimality. The obtained solution may be close to the optimal one, but its quality depends on the approach used and on the characteristics of the particular problem [27,28,29]. In the present work, the TSP is used as a test environment for the analysis of two exact algorithms for finding a minimum Hamiltonian cycle. The first algorithm, denoted as RecursiveHamiltonianCycle (RHC), performs an exhaustive recursive search over the space of all possible solutions. The second algorithm, denoted as PrunedHamiltonianCycleSearch (PHCS), employs a mechanism for early pruning of non-promising branches in order to reduce the number of explored solutions. Through a comparative analysis of the two algorithms, the influence of the employed techniques on the efficiency of the computational process and the execution time is evaluated.
Although the proposed PHCS algorithm is based on the well-established branch-and-bound paradigm, the objectives and contributions of the present study differ from the development of a new pruning rule. The branch-and-bound principle employed by the proposed PHCS procedure is well known in the literature. Therefore, the contribution of the present work is not the introduction of a new pruning principle itself. Instead, the study presents and analyzes a recursive branch-pruning exact search procedure for the Travelling Salesman Problem. It further investigates the influence of the initial upper bound on pruning effectiveness experimentally. In addition, the combined effect of nearest-neighbor initialization and recursive branch pruning on the number of recursive calls and execution time is evaluated while preserving exact optimality.
2. Materials and Methods
To evaluate the quality of solutions generated by approximation algorithms for a given problem, it is necessary to determine the optimal solution in advance, whenever this is practically feasible. For this purpose, two algorithms based on exhaustive exploration of the solution space have been implemented for the exact solution of the Travelling Salesman Problem (TSP). The first algorithm represents a modified version of a recursive approach presented in a previous study by the author [30], adapted for finding a minimum Hamiltonian cycle. The second algorithm employs a mechanism for the early pruning of non-promising branches in order to reduce the number of explored solutions. By analyzing the obtained results, it is possible to evaluate the influence of the selected algorithmic approach on the execution time of the computational process.
The two algorithms for the exact solution of the TSP operate on the set of vertices Vertices = {vertex1, vertex2, …, vertexk} of the graph under consideration. Each permutation of these vertices defines a possible order for their traversal when constructing a Hamiltonian cycle. Since the number of all possible permutations of k elements is k!, the solution space grows factorially as the number of vertices increases. The generation of permutations is performed recursively. After fixing a vertex at position p, all possible arrangements of the remaining k − p vertices are generated. For each generated permutation, the length of the corresponding Hamiltonian cycle is calculated and the obtained solution is evaluated. The proposed algorithms assume that all edge weights are non-negative. This assumption is satisfied by the investigated test instances, where edge weights are defined as Euclidean distances between pairs of vertices. Under this condition, extending a partially constructed route cannot decrease its accumulated cost, which guarantees the correctness of the pruning strategy employed by the PHCS algorithm.
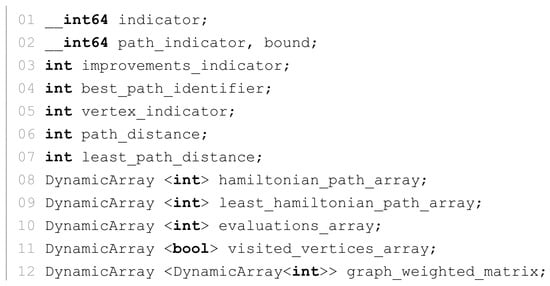
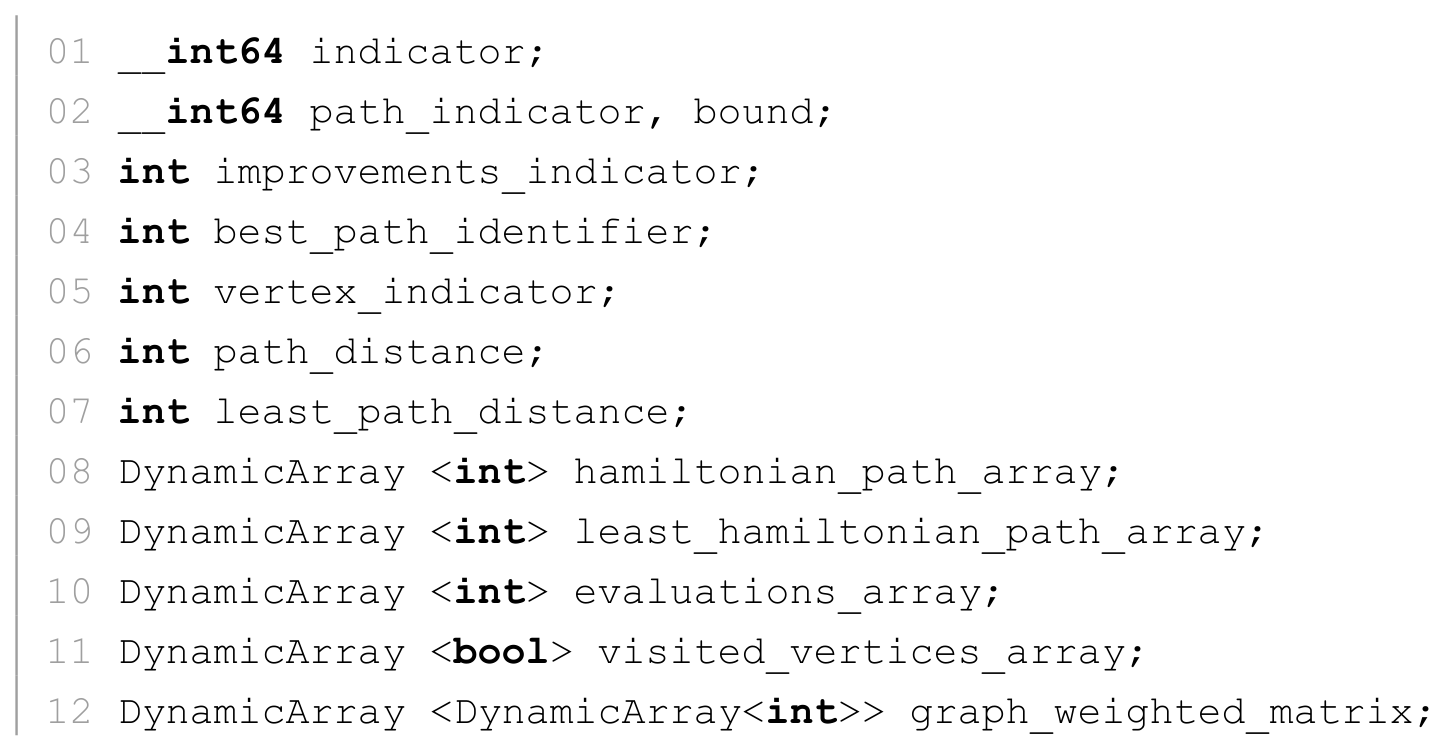
For the implementation of the two algorithms, several global data structures have been defined, including variables and dynamic arrays. These structures are used to store the current state of the computational process and are accessible from all functions of the software implementation. The list of these structures and their declarations is presented in Figure 1 (C++).
Figure 1.
Declarations of the global variables and dynamic arrays.
The variable indicator of type __int64 is used as a counter for the recursive calls performed during the execution of the algorithms. The variable path_indicator, also of type __int64, stores the number of generated and evaluated Hamiltonian cycles. The variable bound, also declared as __int64, stores the maximum number of Hamiltonian cycles considered during the search procedure and serves as an upper bound for the cycle counter. The variable improvements_indicator records the number of cases in which a Hamiltonian cycle with a shorter length than the best solution found so far has been identified. This variable is used by the optimized version of the algorithm, which applies a mechanism for the early pruning of non-promising branches. Under this approach, whenever the length of a partially constructed Hamiltonian cycle becomes greater than the length of the best cycle found so far, the further expansion of the corresponding solution is terminated. The reason is that all edge weights are assumed to be non-negative; therefore, adding new vertices and edges cannot decrease the accumulated route length and cannot lead to a shorter final cycle. In this way, the generation and evaluation of solutions that cannot improve the current optimum are avoided. The variable vertex_indicator of type int stores the number of vertices in the graph under consideration and is used during the traversal of all vertices. The length of the currently constructed Hamiltonian cycle is stored in the variable path_distance, whereas the length of the shortest cycle found so far is stored in the variable least_path_distance. Both variables are of type int.
The remaining globally declared structures are dynamic arrays. In these structures, memory for storing their elements is allocated during program execution, allowing their size to be determined dynamically according to the size of the problem under consideration. The dynamic array hamiltonian_path_array stores the indices of the vertices that form the currently constructed Hamiltonian cycle. Its size is vertex_indicator + 1, where the last element is equal to the first vertex of the cycle. In this way, the route is closed and a complete Hamiltonian cycle is formed. The dynamic array least_hamiltonian_path_array also has a size of vertex_indicator + 1 and stores the vertices of the shortest Hamiltonian cycle found so far. Traversing the vertices in the stored order produces a solution with the minimum length among all solutions considered up to that point. The dynamic array visited_vertices_array contains Boolean elements and is used to indicate whether a given vertex has already been visited within the current recursive branch. Its size is vertex_indicator + 1 and it is utilized by all implemented algorithms. The last dynamic structure, graph_weighted_matrix, represents the graph weight matrix. Each of its elements stores the length (weight) of the edge between the corresponding pair of vertices. If no edge exists between two vertices, a zero value is stored in the corresponding matrix cell. The dimensions of the matrix are vertex_indicator × vertex_indicator.
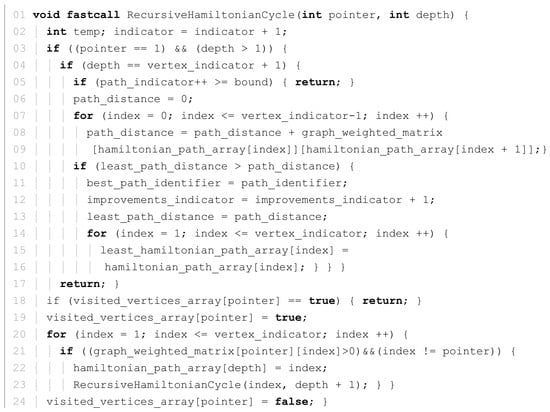
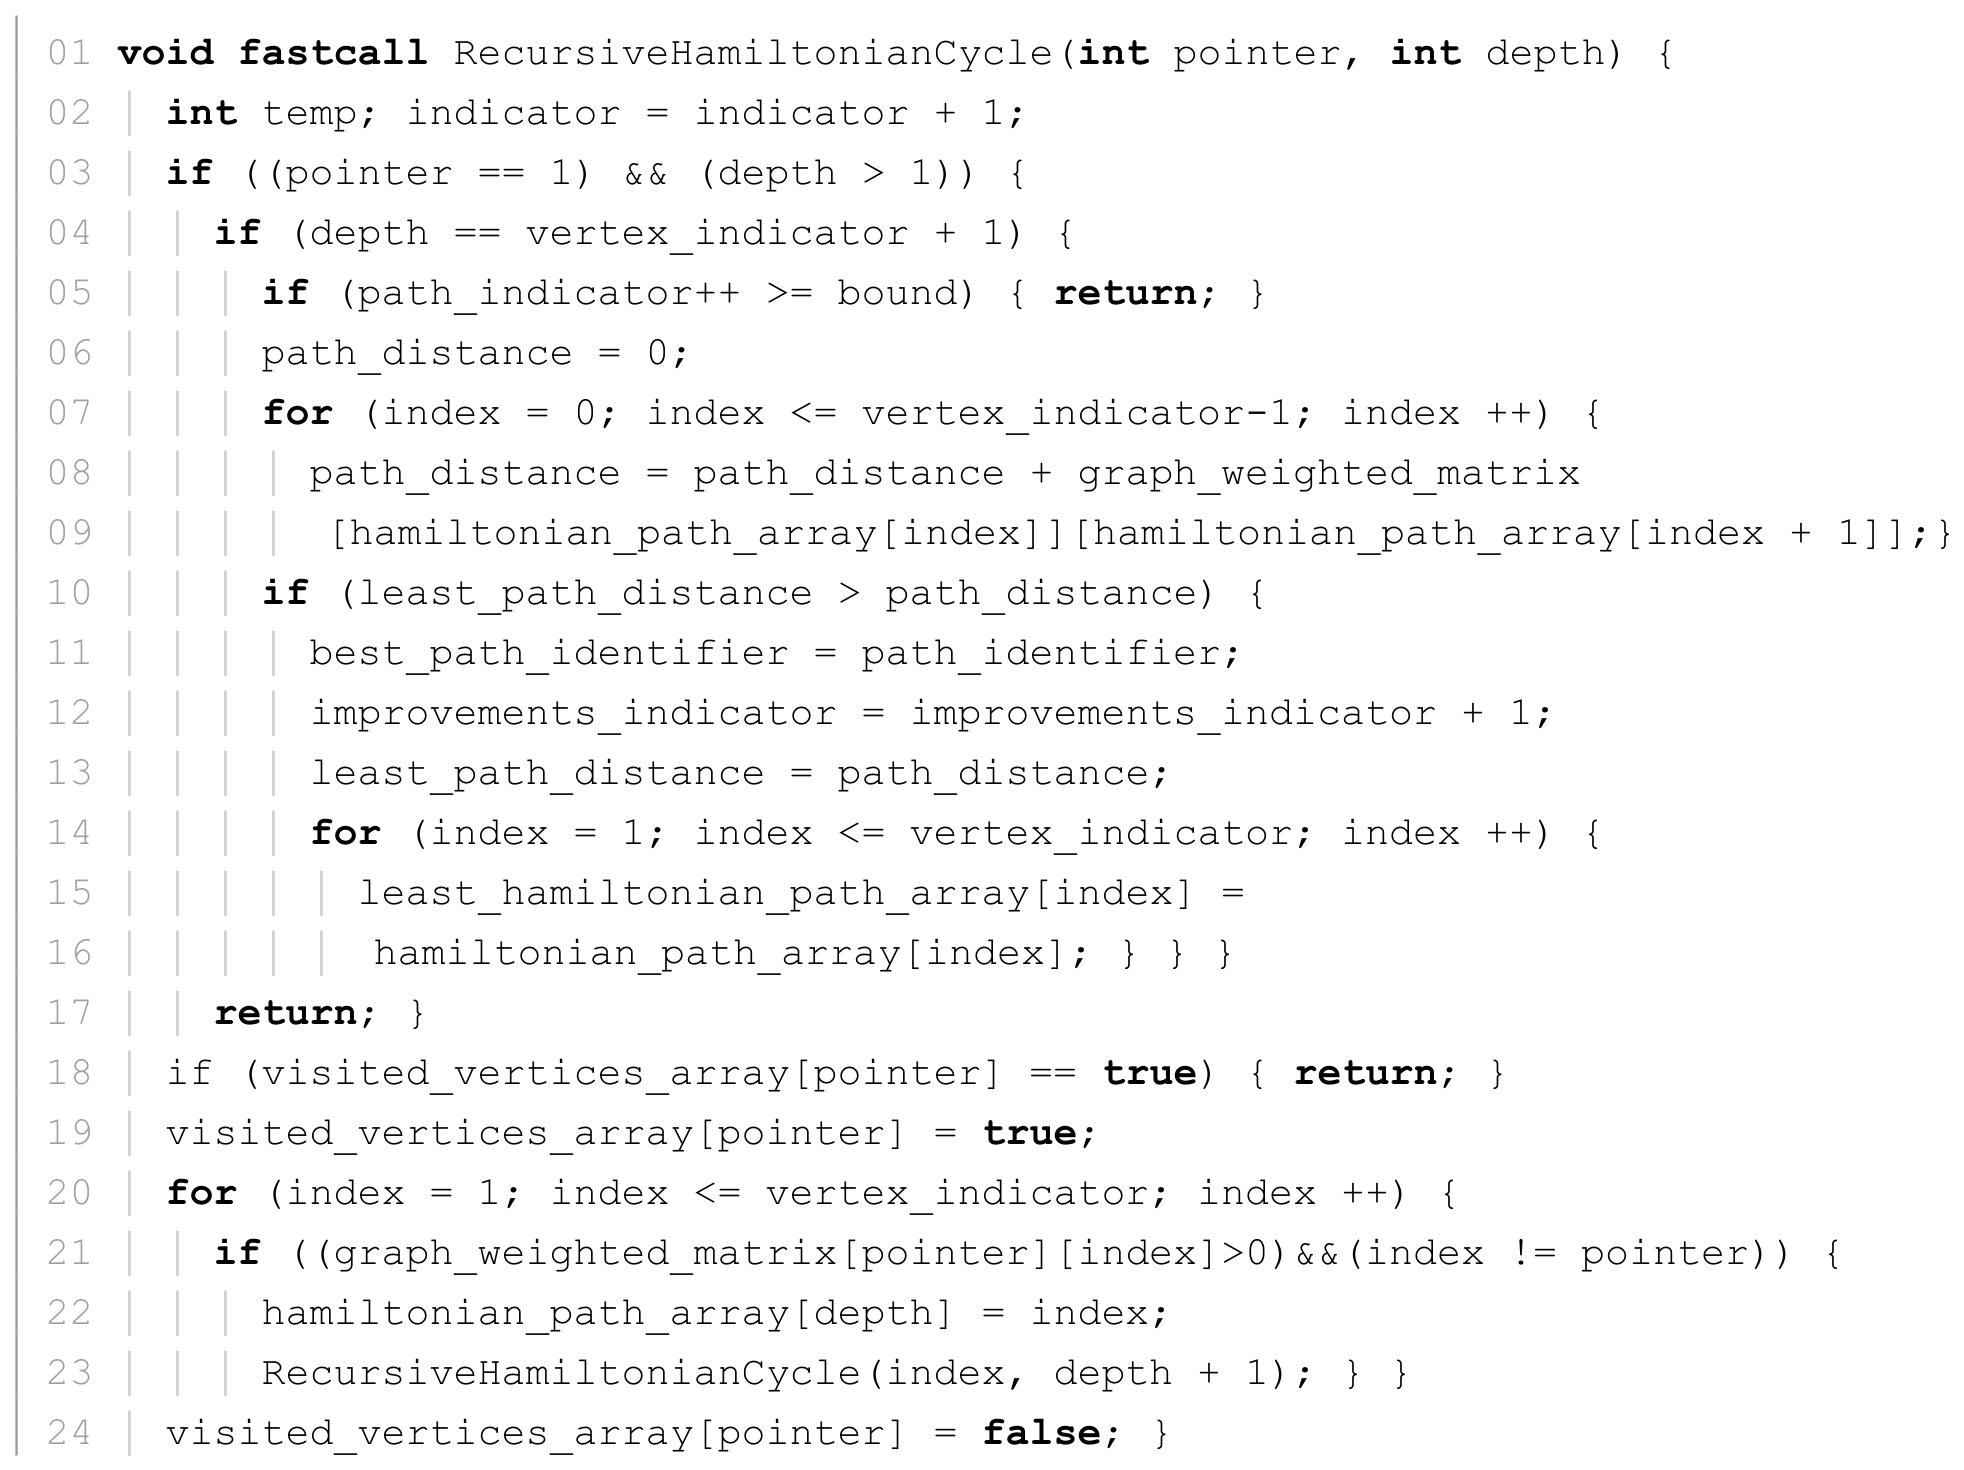
Figure 2 presents the implementation of the first algorithm for the exact solution of the Travelling Salesman Problem. The algorithm employs recursive depth-first search (DFS) with backtracking to generate all valid Hamiltonian cycles in the graph under consideration. Whenever a complete Hamiltonian cycle is generated, its length is calculated and compared with the length of the best solution found so far. To reduce redundant representations of the same Hamiltonian cycle, the search is always initiated from vertex 1. Consequently, cyclic rotations of the same Hamiltonian cycle are not generated repeatedly.
Figure 2.
Implementation of the recursive algorithm for the exact solution of the TSP (RHC).
The algorithm uses a modification of the depth-first search (DFS) method. The RecursiveHamiltonianCycle function is called recursively on line 23. The process continues until all valid Hamiltonian cycles starting from the first vertex and passing through all remaining vertices of the graph have been generated. When the condition on line 4 is satisfied, the current Hamiltonian path is closed by returning to the starting vertex, thereby forming a complete Hamiltonian cycle. The length of the newly formed cycle is calculated on lines 6–9 by summing the weights of the corresponding edges. The obtained value is then compared with the length of the best solution found so far (line 10). If the current cycle is shorter, its length is stored in the variable least_path_distance, and the sequence of vertices is copied into the array least_hamiltonian_path_array (lines 11–16). If the vertex whose index is stored in the pointer has already been visited within the current recursive branch, the execution of the function is terminated and backtracking is performed (line 18). Otherwise, the vertex is marked as visited using the array visited_vertices_array (line 19), after which all adjacent vertices that can participate in the continuation of the current Hamiltonian cycle are examined sequentially (lines 20–22). After the recursive call has finished, the vertex is marked as unvisited again (line 24). This technique allows all possible branches in the search tree to be explored and represents the fundamental mechanism of the backtracking method. The optimization implemented on line 5 prevents the generation of more Hamiltonian cycles than the theoretical number obtainable when the starting vertex is fixed. Since the search is always initiated from vertex 1, cyclic rotations of the same Hamiltonian cycle are not generated repeatedly. Consequently, the search space is reduced from n! possible vertex orderings to (n − 1)! candidate tours. The time complexity of the algorithm is factorial and is of the order of O((n − 1)!). This factorial complexity results from the exhaustive generation and evaluation of all unique Hamiltonian cycles in the graph under consideration.
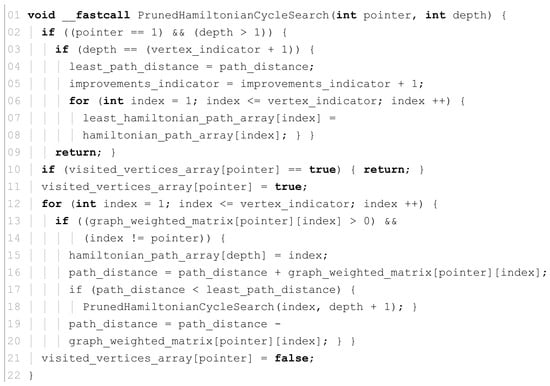
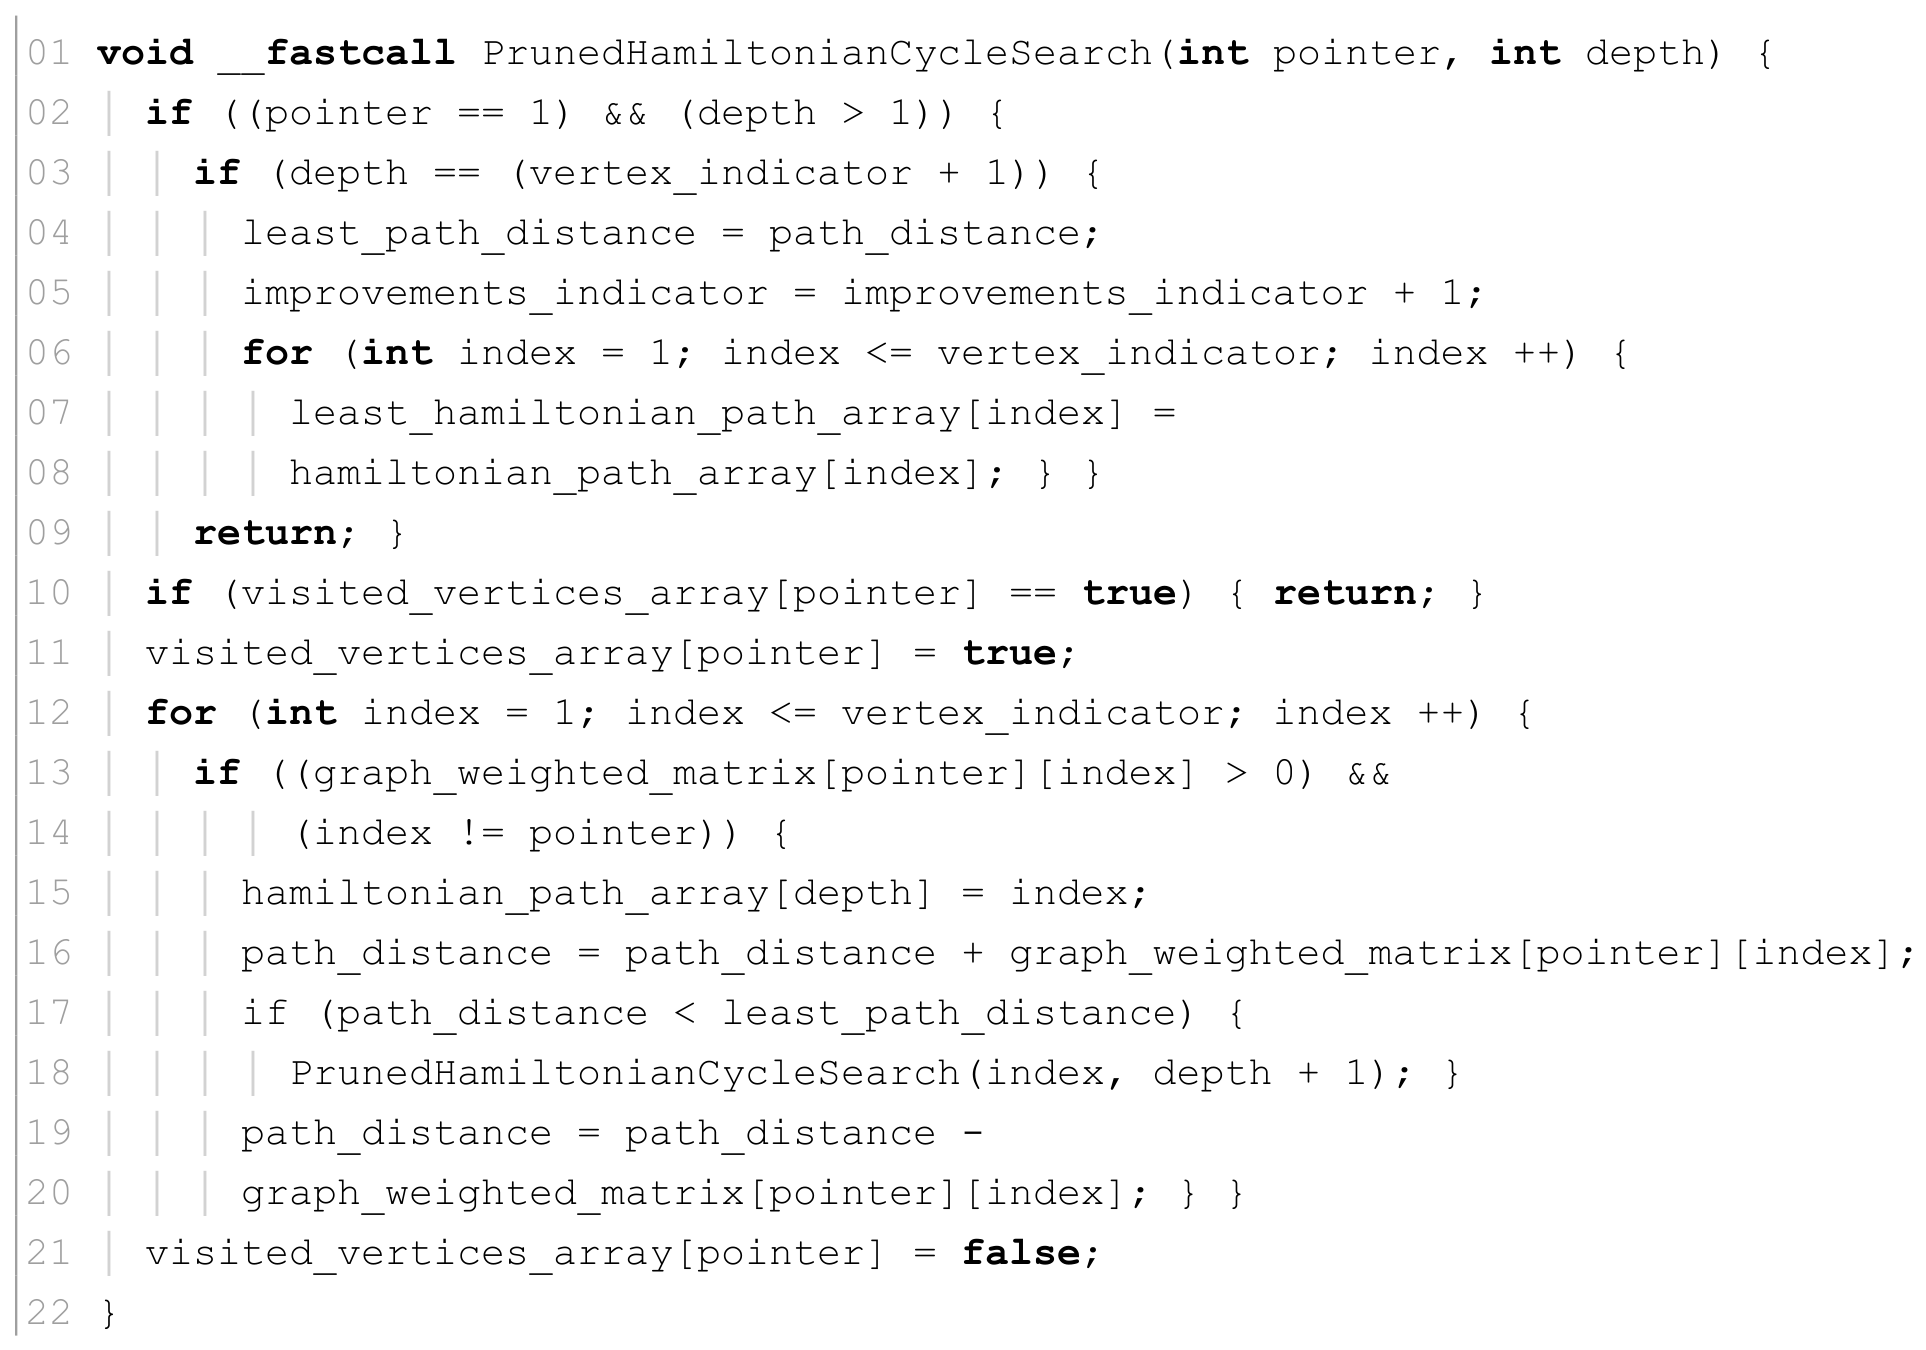
In this section, an optimized algorithm for the exact solution of the Travelling Salesman Problem is presented. Similar to the RecursiveHamiltonianCycle algorithm, it employs recursive depth-first search and backtracking to generate Hamiltonian cycles. The main difference lies in the pruning strategy applied during the construction of the solution. Whenever the current length of a partially constructed Hamiltonian cycle exceeds the length of the best cycle found so far, the further expansion of the corresponding branch is terminated. This allows a significant reduction in the number of explored solutions and, consequently, in the execution time. The implementation of the algorithm is presented in Figure 3.
Figure 3.
Implementation of the optimized algorithm for the exact solution of the TSP (PHCS).
Similar to the RecursiveHamiltonianCycle algorithm, this algorithm also employs recursive depth-first search (DFS) with backtracking. The function PrunedHamiltonianCycleSearch recursively calls itself on line 18. When the condition on lines 2–8 is satisfied, a complete Hamiltonian cycle has been constructed. In this case, the cycle length is stored in the variable least_path_distance (line 4), the counter improvements_indicator is incremented by one (line 5), and the vertices of the obtained solution are copied into the array least_hamiltonian_path_array (lines 6–8). During each recursive call, the weight of the newly added graph edge is added to the current length of the partially constructed cycle (path_distance) (line 16). A check is then performed to determine whether the obtained value is smaller than the length of the best solution found so far (line 17). Only if this condition is satisfied does the algorithm continue the recursive exploration of the corresponding branch (line 18). If the current length of the partially constructed cycle becomes greater than or equal to the value of least_path_distance, the execution of the corresponding branch is terminated. After returning from the recursive call, the last added edge is removed from the current solution by decreasing the value of path_distance (lines 19–20). In this way, a mechanism for the early pruning of non-promising solutions that cannot improve the current optimum is implemented. The effect of this optimization is a significant reduction in the number of explored states in the search tree. Nevertheless, the asymptotic worst-case time complexity of the algorithm remains factorial, of order O(n!), since under unfavorable input conditions it may still be necessary to consider almost all possible Hamiltonian cycles. In practice, however, the pruning mechanism substantially reduces the number of generated solutions and leads to a significant decrease in execution time.
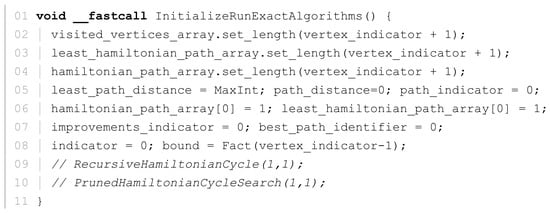
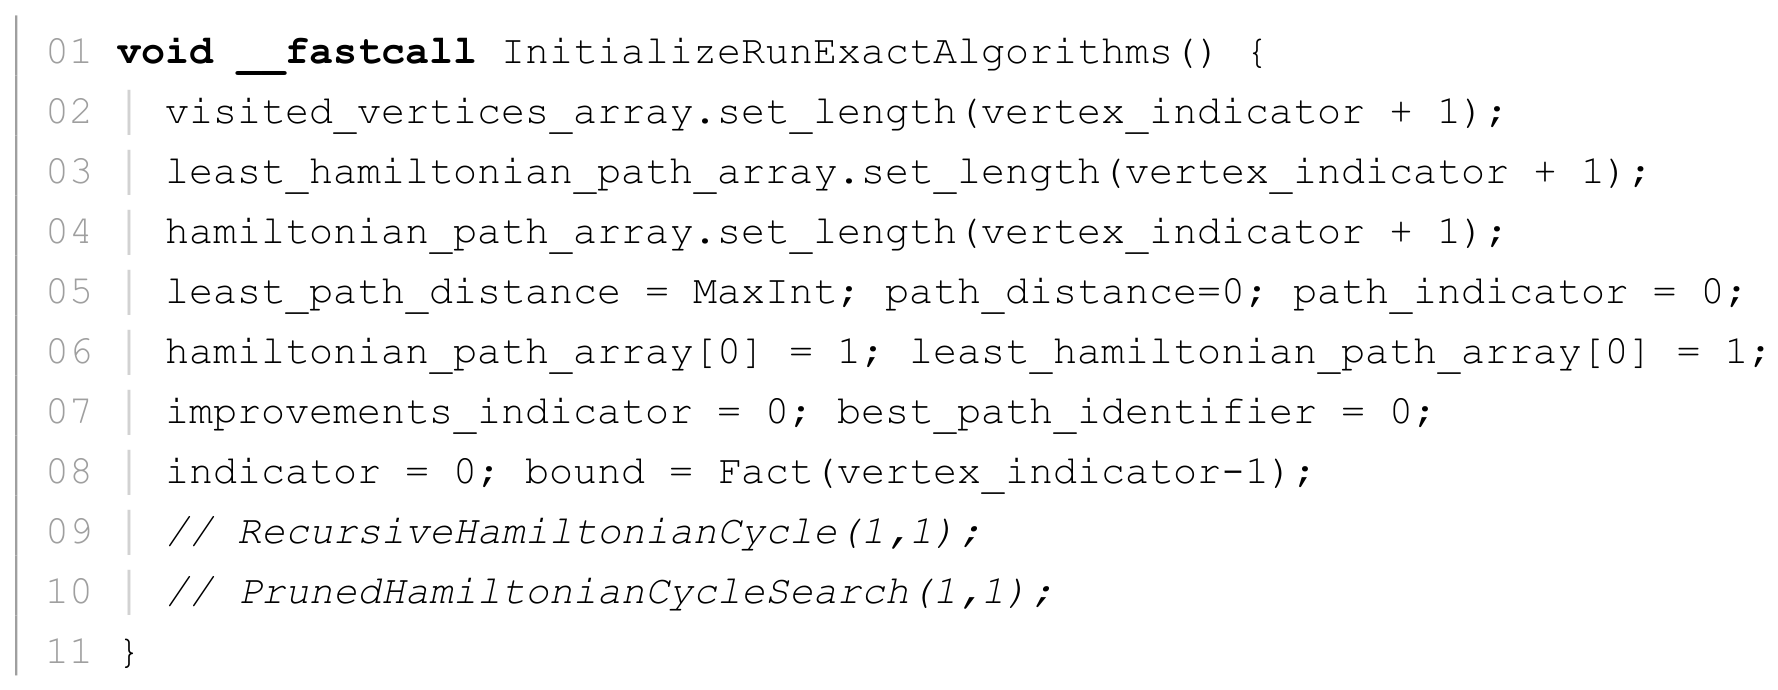
Both exact algorithms for solving the TSP are initialized and executed through the InitializeRunExactAlgorithms function. This function prepares the required data structures, initializes the global variables, and invokes the selected algorithm. Its implementation is presented in Figure 4.
Figure 4.
Implementation of the initialization and execution function for the exact algorithms.
Memory allocation for the dynamic arrays used by the algorithms is performed on lines 2–4. On lines 5–8, the global variables and the auxiliary structures required for the execution of the computational process are initialized. The value of the variable bound is calculated on line 8 and corresponds to the number of Hamiltonian tours generated when the starting vertex is fixed to vertex 1. The execution of a specific algorithm is performed by calling the corresponding function on line 9 or line 10. Depending on the selected experiment, one of the two function calls is enabled, while the other remains commented out. In this way, both algorithms use the same initialization process and can be compared under identical initial conditions.
The execution time of the two algorithms can be measured using the GetTickCount function. This function returns the number of milliseconds that have elapsed since the operating system was started. To determine the execution time, the function must be called immediately before and immediately after the execution of the algorithm under investigation, with the difference between the two values representing the duration of the computational process. Due to the multitasking nature of modern operating systems, the measured execution time may vary between different runs. When a more precise estimation of execution time is required, the algorithms may be executed multiple times, and the arithmetic mean of the measured execution times may be used for analysis. Such an approach is particularly useful when the measured execution times are close to one another and small variations may affect the interpretation of the results.
In the experiments reported in this paper, single-run measurements were used. Although repeated executions and averaging can further reduce the influence of operating-system multitasking, such an approach was not considered necessary because the observed execution times differ by several orders of magnitude, ranging from seconds to days. Therefore, small timing fluctuations do not affect the overall conclusions regarding the comparative performance and scalability of the investigated algorithms. All reported execution times for the PHCS algorithm with nearest-neighbor initialization include the time required to generate the initial nearest-neighbor tour.
3. Results
To evaluate the practical applicability of the proposed exact algorithms, a series of computational experiments was conducted using complete weighted undirected graphs containing between 12 and 21 vertices. The coordinates of all vertices were generated in a two-dimensional space, and the weight of each edge was defined as the Euclidean distance between the corresponding pair of vertices. In this way the distance d(i, j) between two vertices i and j was calculated as and rounded to the nearest integer using the Round function before being stored as an edge weight. The investigated graphs were complete graphs, meaning that every pair of vertices was connected by an edge. Consequently, for a graph containing n vertices, the number of edges m was equal to n(n − 1)/2, while the degree d of each vertex was n − 1. The graphs were constructed incrementally. Starting from graph G12, each subsequent graph was created by adding one additional vertex together with all edges connecting it to the existing vertices. In this way, graph Gn contained all vertices and edges of graph Gn−1. The vertices were added according to their numbering and labels given in Table 1. Thus, graph G12 contains vertices 1–12 (a–l), graph G13 additionally includes vertex 13 (m), graph G14 additionally includes vertex 14 (n), and so forth until graph G21, which contains all vertices listed in Table 1. It should be noted that the investigated graphs were generated as a single incremental sequence, where each graph contains all vertices and edges of the previous graph. This design facilitates a clear analysis of how the algorithms scale with increasing problem size. However, the obtained results are based on one family of related graph instances and may not fully represent the behavior of the algorithms on all possible graph configurations. Additional experiments using independently generated graph instances constitute a promising direction for future research. The labels and coordinates of the vertices are presented in Table 1.
Table 1.
Vertex coordinates for graph G_21_210.
For a complete undirected graph, the number of unique Hamiltonian cycles is (n − 1)!/2. In the implementation investigated in this study, the starting vertex is fixed, resulting in the generation of (n − 1)! candidate tours. As a consequence, the size of the solution space grows factorially with increasing values of n. The rapid growth of the solution space demonstrates the computational difficulty of the Travelling Salesman Problem and motivates the search for optimization techniques capable of reducing the number of explored states. Table 2 summarizes the characteristics of the investigated graphs.
Table 2.
Characteristics of the investigated graphs.
The first series of experiments was aimed at comparing the performance of the RecursiveHamiltonianCycle (RHC) algorithm and the PrunedHamiltonianCycleSearch (PHCS) algorithm. Both algorithms always produced identical optimal Hamiltonian cycles and identical objective values. Therefore, the comparison focuses exclusively on computational efficiency. The experiments were performed on a standard computer configuration running Windows 11 Pro 64-bit (Microsoft Corporation, Redmond, WA, USA) with the following hardware configuration: Intel® Core™ i7-4712MQ CPU @ 2.30 GHz (Intel Corporation, Santa Clara, CA, USA) and 8.00 GB RAM. The experimental application was compiled for the 64-bit platform and executed under the 64-bit operating system, ensuring the use of 64-bit integer arithmetic during the experiments.
As can be observed from Table 3, the optimal Hamiltonian cycle and its length are identical for both algorithms in all investigated graph instances G12–G16. This agreement provides experimental verification of the correctness of the pruning strategy for the instances where a direct comparison between the two exact algorithms is computationally feasible. For larger instances, direct verification using RHC was not possible because of the prohibitive computational requirements of exhaustive search. Nevertheless, the correctness of PHCS follows from its exact-search nature and from the pruning condition, which eliminates only branches whose partial path length is not smaller than the best complete solution found so far. Since all edge weights are non-negative, extending such a partial solution cannot lead to a shorter Hamiltonian cycle.
Table 3.
Comparison between RHC and PHCS.
The obtained results demonstrate that the pruning mechanism substantially reduces the number of recursive calls required to identify the optimal solution. For graph G16, the recursive exhaustive-search algorithm required more than seven days of execution time, whereas the optimized PHCS algorithm completed the search in approximately 17 s. As a result, a substantial improvement in performance was achieved. The effectiveness of the pruning mechanism increases with graph size, as longer partial paths are more likely to exceed the current best solution, leading to the earlier termination of non-promising branches. As illustrated in Figure 5, the gap between the numbers of recursive calls performed by the two algorithms widens considerably as the graph size increases.
Figure 5.
Comparison of recursive calls performed by RHC and PHCS for graphs G12–G16 (logarithmic scale).
Figure 5 confirms that both algorithms exhibit factorial growth in the number of recursive calls. However, the pruning mechanism significantly limits the expansion of the search tree, resulting in several orders of magnitude fewer recursive calls for the PHCS algorithm.
The experimental results for graph G17 revealed an important characteristic of the PHCS algorithm. Initially, the algorithm starts with a very large upper bound (MaxInt). During the search process, increasingly shorter Hamiltonian cycles are identified until the optimal solution is reached. To investigate the influence of the initial upper bound, the experiment was repeated using a high-quality Hamiltonian cycle as an initial reference solution.
The optimal solution remained unchanged and had a length of 1681 px in both experiments. The detailed comparison of the two experiments is presented in Table 4. However, the number of recursive calls decreased by a factor of approximately 3.8, while the execution time decreased by a factor of approximately 3.6. These results indicate that the quality of the initial upper bound has a significant influence on the efficiency of the pruning strategy. Based on the observations obtained for graph G17, an additional optimization strategy was introduced. Before executing the PHCS algorithm, a nearest-neighbor heuristic was applied. The heuristic was executed once from each graph vertex, and the shortest Hamiltonian cycle obtained by the heuristic was selected as the initial upper bound for the exact search procedure. Although this initial solution does not guarantee optimality, it provides a relatively short Hamiltonian cycle, allowing the PHCS algorithm to eliminate a large number of non-promising branches at an early stage of the search process. The nearest-neighbor initialization strategy was applied to graphs G18–G21. The experimental results are summarized in Table 5. Path lengths reported in the columns NN Solution, Optimal Solution, and Difference are expressed in pixels. These experiments provide a direct quantitative evaluation of the influence of the initial upper bound on branch-pruning effectiveness and demonstrate its impact on the overall computational effort required by the exact search procedure.
Table 4.
Influence of the initial upper bound for graph G17.
Table 5.
Results obtained using Nearest Neighbor initialization followed by PHCS.
Although the G17 experiment clearly demonstrates the benefit of a tighter initial upper bound, the present study does not include a systematic comparison of PHCS executions with and without nearest-neighbor initialization across all graph sizes. Consequently, the reported results should be interpreted as evidence of the effectiveness of the initialization strategy rather than as a complete quantitative assessment of its contribution for every investigated instance.
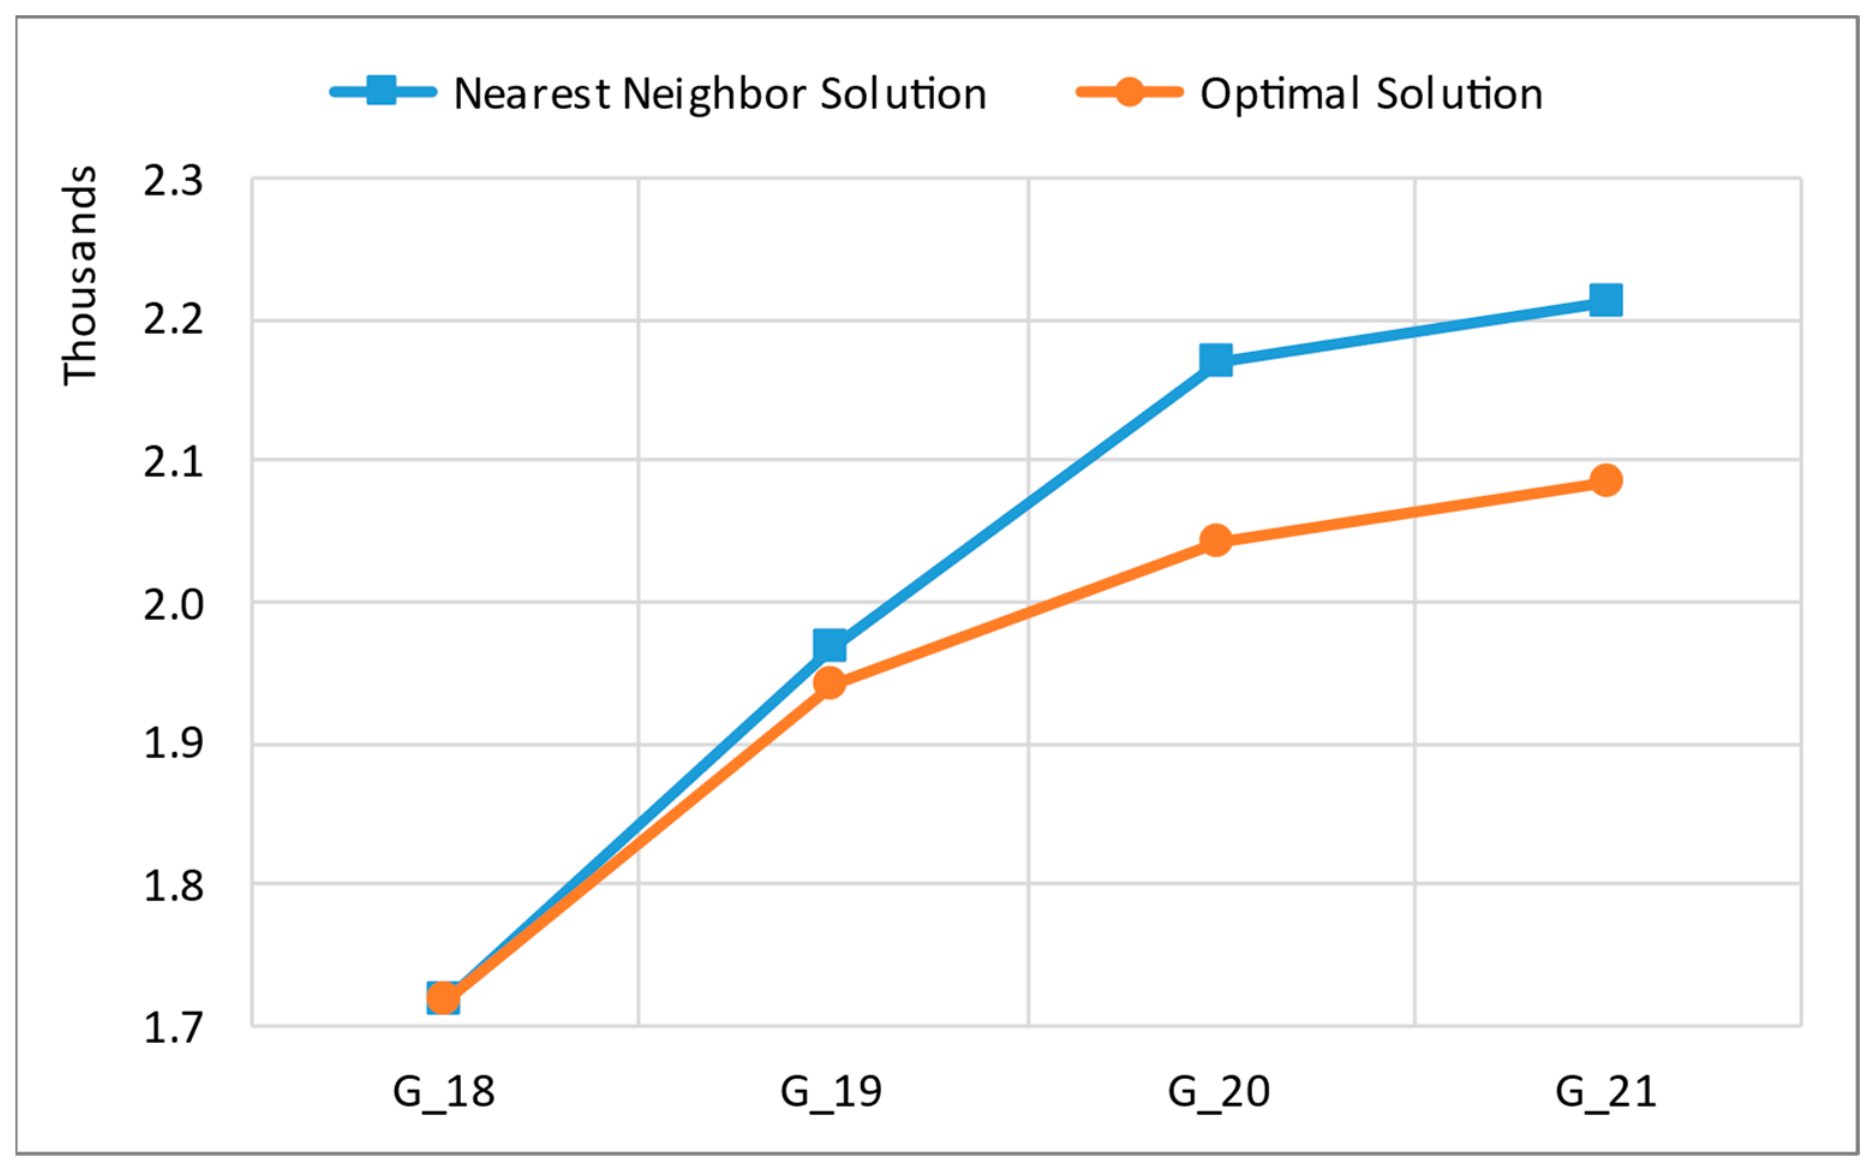
The results demonstrate that the nearest-neighbor heuristic provides solutions that are very close to the optimum, as illustrated in Figure 6. For graph G18, the heuristic directly identified the optimal Hamiltonian cycle. For graphs G19–G21, the difference between the heuristic and optimal solutions remained relatively small, thereby enabling effective pruning during the exact search process.
Figure 6.
Comparison of nearest-neighbor and optimal solutions for graphs G18–G21.
The experimental results demonstrate that all proposed optimization techniques contribute significantly to the practical performance of the exact TSP solver. The pruning mechanism implemented in PHCS dramatically reduces the number of recursive calls compared with exhaustive search while preserving the optimality of the obtained solution. For all graph instances where direct comparison was computationally feasible (G12–G16), PHCS produced exactly the same optimal Hamiltonian cycle as RHC, confirming that the pruning strategy affects only the computational effort required to reach the solution and does not influence its correctness. Furthermore, the obtained results indicate that the effectiveness of pruning increases as the graph size grows. The difference between the numbers of recursive calls performed by the two algorithms becomes progressively larger for graphs containing more vertices, resulting in performance improvements of several orders of magnitude. The experiments also show that the quality of the initial upper bound has a direct impact on the effectiveness of the pruning process. A smaller upper bound leads to earlier elimination of non-promising branches and consequently reduces the number of recursive calls and the overall execution time. The results obtained for graph G17 clearly demonstrate that providing a high-quality initial solution considerably improves the efficiency of the exact search procedure.
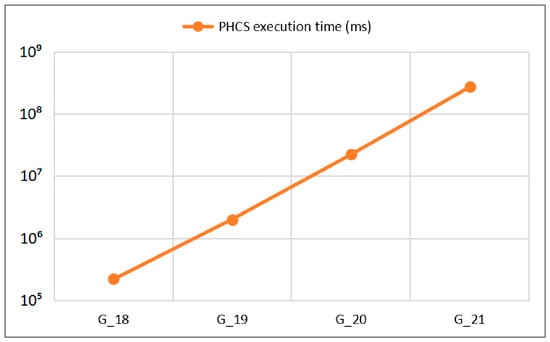
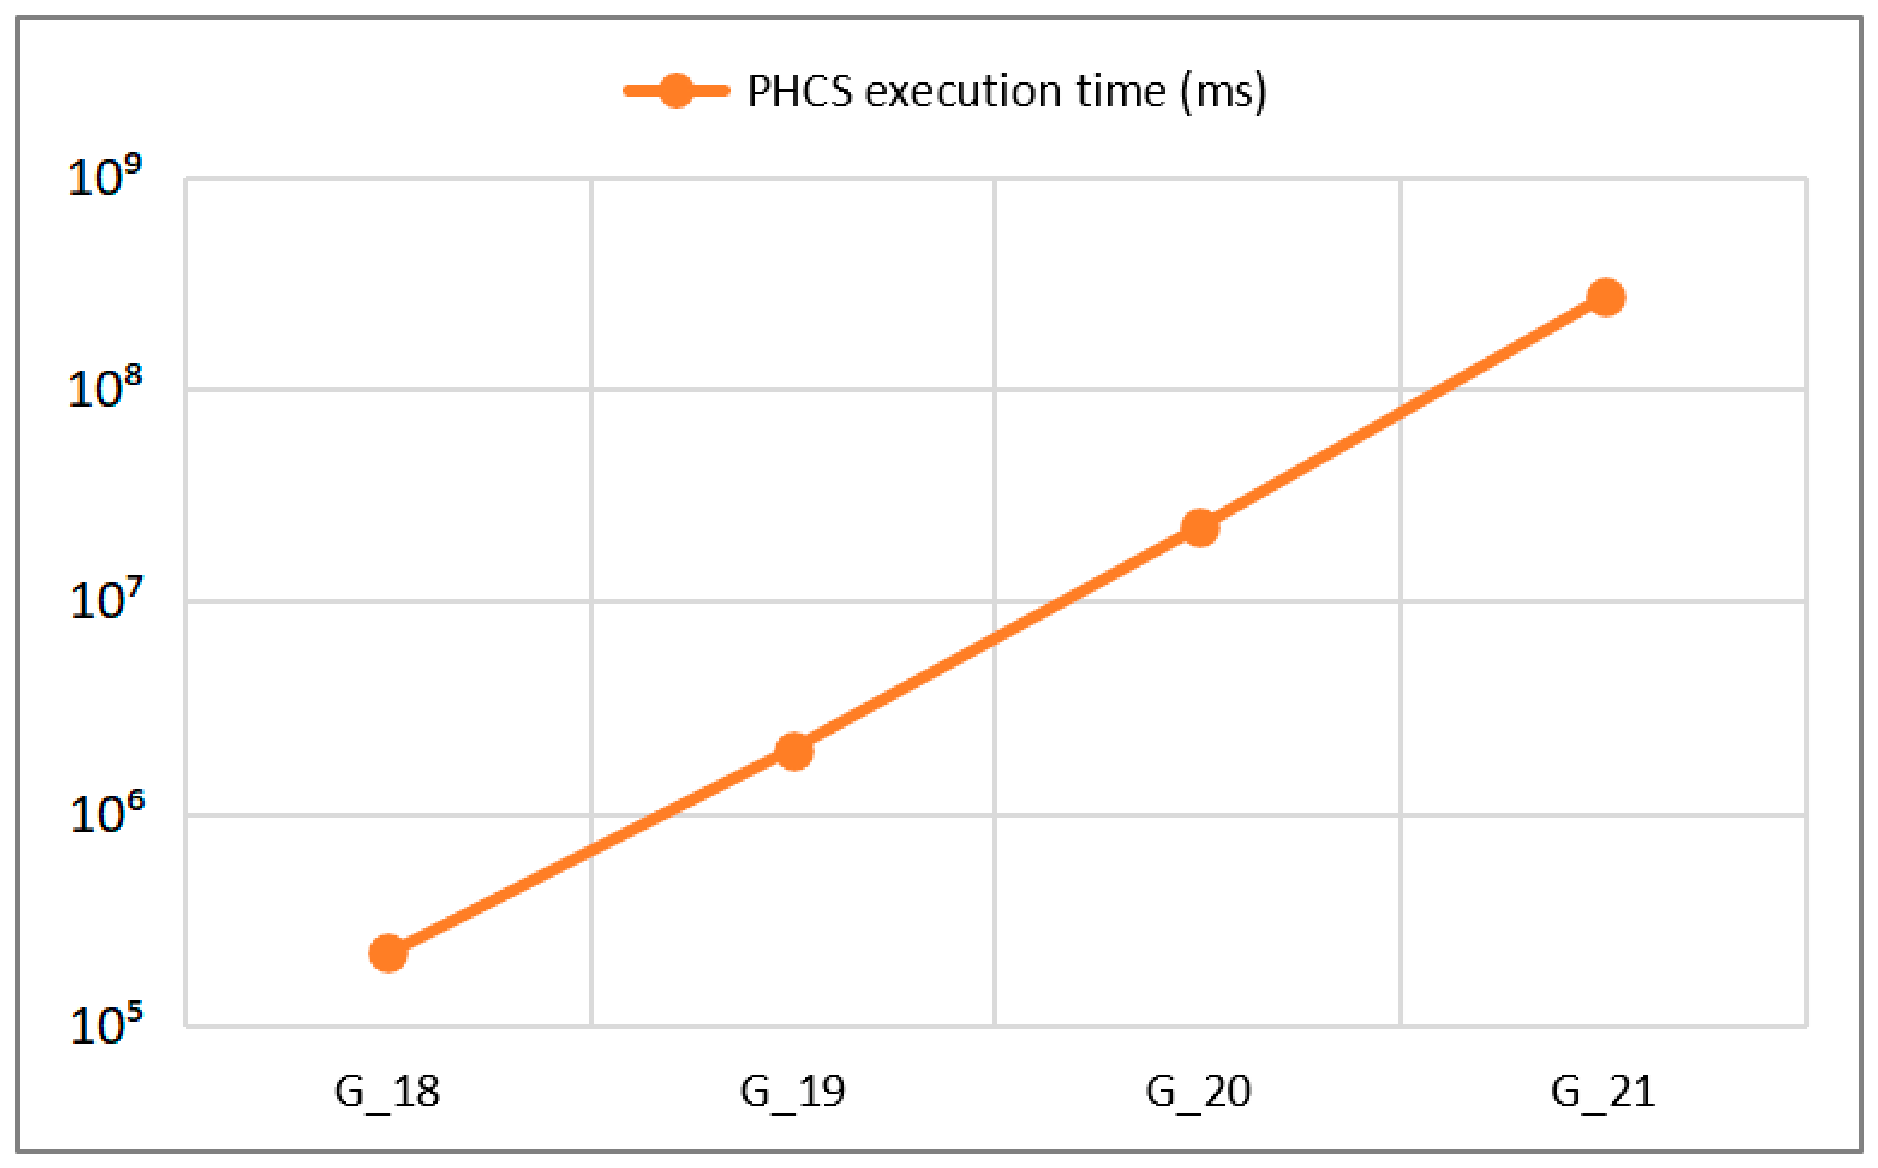
The nearest-neighbor heuristic proved to be an effective method for constructing such an initial upper bound. For graph G18, the heuristic directly identified the optimal Hamiltonian cycle, while for graphs G19–G21 the generated solutions remained very close to the optimal ones. As a result, only a small number of successive improvements were required before the exact algorithm reached the global optimum. This confirms that combining a fast heuristic procedure with an exact branch-pruning search can significantly improve the practical applicability of exact TSP algorithms. Despite all applied optimizations, the computational complexity of the exact solution process remains factorial. The execution time increased from approximately four minutes for graph G18 to more than seventy-six hours for graph G21, as shown in Figure 7. This behaviour reflects the combinatorial nature of the Travelling Salesman Problem and demonstrates that exact algorithms remain computationally demanding even when advanced pruning techniques and high-quality initial solutions are employed.
Figure 7.
PHCS execution time for graphs G18–G21 (logarithmic scale).
Overall, the conducted experiments show that the PHCS algorithm substantially outperforms exhaustive recursive search while maintaining exactness. The results further indicate that the use of a high-quality initial upper bound is one of the key factors affecting the efficiency of the search process. Although the proposed optimization techniques considerably extend the practical applicability of exact TSP algorithms, the rapid factorial growth of the solution space ultimately limits their use to medium-sized graph instances. Within the conducted experiments, graph G21 represented the largest problem instance for which an exact solution could still be obtained within a practically acceptable execution time.
4. Conclusions
The Travelling Salesman Problem is one of the best-known combinatorial optimization problems and is frequently used as a benchmark for evaluating exact and approximate optimization techniques. In the present study, two exact recursive algorithms for finding a minimum Hamiltonian cycle in a complete weighted undirected graph were investigated and compared. The first algorithm, RecursiveHamiltonianCycle (RHC), employs exhaustive recursive generation and evaluation of all unique Hamiltonian cycles. The second algorithm, PrunedHamiltonianCycleSearch (PHCS), introduces an early branch-pruning mechanism that terminates the exploration of partial solutions whenever their current length exceeds the length of the best solution found so far. The experimental results for graph instances G12–G16 demonstrate that both algorithms produce identical optimal solutions, confirming the correctness of the pruning strategy for the instances where direct verification is computationally feasible. A comparative analysis shows that the pruning mechanism dramatically reduces the number of recursive calls and the execution time required to obtain the optimal Hamiltonian cycle. For the investigated graph instances, the performance improvement increased with graph size, reaching several orders of magnitude.
An additional contribution of the study is the analysis of the influence of the initial upper bound used by the pruning mechanism. The experiments reveal that providing a high-quality initial solution significantly improves the efficiency of the exact search procedure. Based on this observation, a nearest-neighbor heuristic was used to construct an initial Hamiltonian cycle before executing the PHCS algorithm. The obtained heuristic solutions were found to be very close to the optimum and, in the case of graph G18, coincided with the optimal solution. This considerably increased the effectiveness of branch pruning and reduced the number of explored states. Despite all applied optimizations, the factorial growth of the search space remains the dominant limiting factor. The execution time increased from several minutes for graph G18 to more than seventy-six hours for graph G21, demonstrating that exact approaches to the TSP remain computationally demanding even when advanced pruning strategies are employed.
Author Contributions
Conceptualization, R.K. and V.K.; methodology, R.K.; software, R.K. and V.K.; formal analysis, R.K.; investigation, R.K.; data curation, V.K.; writing—original draft preparation, R.K. and V.K.; writing—review and editing, R.K.; visualization, V.K. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Data Availability Statement
The data involved in the paper are available upon reasonable request to the corresponding author.
Acknowledgments
The authors would like to thank the reviewers for their constructive comments.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Cormen, T.H.; Leiserson, C.E.; Rivest, R.L.; Stein, C. Introduction to Algorithms; MIT Press: Cambridge, MA, USA, 2009. [Google Scholar]
- Sedgewick, R.; Wayne, K. Algorithms, 4th ed.; Pearson Education: Hong Kong, China, 2011. [Google Scholar]
- Skiena, S.S. The Algorithm Design Manual, 2nd ed.; Springer: Berlin/Heidelberg, Germany, 2012. [Google Scholar]
- Knuth, D.E. The Art of Computer Programming, Vol. 3: Sorting and Searching; Addison-Wesley: Reading, MA, USA, 2011. [Google Scholar]
- McCauley, R.; Hanks, B.; Fitzgerald, S.; Murphy, L. Recursion vs. Iteration: An Empirical Study of Comprehension Revisited. In Proceedings of the 46th ACM Technical Symposium on Computer Science Education, Kansas City, MO, USA, 4–7 March 2015; pp. 350–355. [Google Scholar]
- Bhaskar, S. A Difference in Complexity Between Recursion and Tail Recursion. Theory Comput. Syst. 2017, 60, 299–313. [Google Scholar] [CrossRef] [Scilit]
- Liu, Y.A.; Stoller, S.D. From Recursion to Iteration: What Are the Optimizations? ACM SIGPLAN Not. 2000, 34, 73–82. [Google Scholar]
- Sundararajah, K.; Sakka, L.; Kulkarni, M. Locality Transformations for Nested Recursive Iteration Spaces. Proc. ACM SIGARCH Comput. Archit. News 2017, 45, 281–295. [Google Scholar] [CrossRef] [Scilit]
- Insa, D.; Silva, J. Automatic Transformation of Iterative Loops into Recursive Methods. Inf. Softw. Technol. 2015, 58, 95–109. [Google Scholar] [CrossRef] [Scilit]
- Musa, A.; Dubach, C. Automatic Recursion Elimination Using Recurrence Relations for Synthesis of Stack-Free Hardware. In Proceedings of the Asia and South Pacific Design Automation Conference (ASP-DAC), Hong Kong, China, 19–22 January 2026; pp. 482–488. [Google Scholar] [CrossRef] [Scilit]
- Li, X.; Zhang, Q.; Wang, G.; Shi, Z.; Guan, Y. Reasoning About Iteration and Recursion Uniformly Based on Big-Step Semantics. Lect. Notes Comput. Sci. 2021, 13071, 61–80. [Google Scholar] [CrossRef] [Scilit]
- Leijen, D.; Lorenzen, A.F. Tail Recursion Modulo Context: An Equational Approach. J. Funct. Program. 2025, 35, e22. [Google Scholar] [CrossRef] [Scilit]
- Wilson, R.J. Introduction to Graph Theory, 5th ed.; Prentice Hall: Englewood Cliffs, NJ, USA, 2010. [Google Scholar]
- Benjamin, A.; Chartrand, G.; Zhang, P. The Fascinating World of Graph Theory; Princeton University Press: Princeton, NJ, USA, 2017. [Google Scholar]
- Alekseev, V.E.; Boliac, R.; Korobitsyn, D.V.; Lozin, V.V. NP-hard Graph Problems and Boundary Classes of Graphs. Theor. Comput. Sci. 2007, 389, 219–236. [Google Scholar] [CrossRef] [Scilit]
- Alanzi, E.; Menai, M.E.B. Solving the Traveling Salesman Problem with Machine Learning: A Review of Recent Advances and Challenges. Artif. Intell. Rev. 2025, 58, 267. [Google Scholar] [CrossRef] [Scilit]
- Wang, Q.; Tang, C. Deep Reinforcement Learning for Transportation Network Combinatorial Optimization: A Survey. Knowl.-Based Syst. 2021, 233, 107526. [Google Scholar] [CrossRef] [Scilit]
- Cappart, Q.; Chételat, D.; Khalil, E.; Lodi, A.; Morris, C.; Veličković, P. Combinatorial Optimization and Reasoning with Graph Neural Networks. J. Mach. Learn. Res. 2023, 24, 1–61. [Google Scholar]
- Sciandra, L.; Esposito, R.; Grosso, A.; Sacerdote, L.; Zucca, C. Graph Convolutional Branch and Bound. Eur. J. Oper. Res. 2026, 334, 798–809. [Google Scholar] [CrossRef] [Scilit]
- Lyu, Z.; Islam, M.Z.; Yu, A.J. A Scalable and Adaptable Supervised Learning Approach for Solving the Traveling Salesman Problems. IEEE Trans. Intell. Transp. Syst. 2024, 25, 17092–17104. [Google Scholar] [CrossRef] [Scilit]
- Wang, S.; Rao, W.; Hong, Y. A Distance Matrix Based Algorithm for Solving the Traveling Salesman Problem. Oper. Res. 2020, 20, 1505–1542. [Google Scholar] [CrossRef] [Scilit]
- Liu, S.; Zhang, Y.; Tang, K.; Yao, X. How Good is Neural Combinatorial Optimization? A Systematic Evaluation on the Traveling Salesman Problem. IEEE Comput. Intell. Mag. 2023, 18, 14–28. [Google Scholar] [CrossRef] [Scilit]
- Perera, J.; Liu, S.H.; Mernik, M.; Črepinšek, M.; Ravber, M. A Graph Pointer Network-Based Multi-Objective Deep Reinforcement Learning Algorithm for Solving the Traveling Salesman Problem. Mathematics 2023, 11, 437. [Google Scholar] [CrossRef] [Scilit]
- Barbosa, L.H.; Uchoa, E. A Branch-Cut-and-Price Algorithm for the Traveling Salesperson Problem with Hotel Selection. Comput. Oper. Res. 2020, 123, 104986. [Google Scholar] [CrossRef] [Scilit]
- de Berg, M.; Bodlaender, H.L.; Kisfaludi-Bak, S.; Kolay, S. An ETH-Tight Exact Algorithm for Euclidean TSP. SIAM J. Comput. 2023, 52, 740–760. [Google Scholar] [CrossRef] [Scilit]
- Pereira, A.H.; Mateus, G.R.; Urrutia, S.A. Valid Inequalities and Branch-and-Cut Algorithm for the Pickup and Delivery Traveling Salesman Problem with Multiple Stacks. Eur. J. Oper. Res. 2022, 300, 207–220. [Google Scholar] [CrossRef] [Scilit]
- Kralev, V.; Kraleva, R. Combining Genetic Algorithm with Local Search Method in Solving Optimization Problems. Electronics 2024, 13, 4126. [Google Scholar] [CrossRef] [Scilit]
- Wei, B.; Xing, Y.; Xia, X.; Gui, L. A Novel Particle Swarm Optimization with Genetic Operator and Its Application to TSP. Int. J. Cogn. Inform. Nat. Intell. 2021, 15, A25. [Google Scholar] [CrossRef] [Scilit]
- Polnik, W.; Stobiecki, J.; Byrski, A.; Kisiel-Dorohinicki, M. Ant Colony Optimization-Evolutionary Hybrid Optimization with Translation of Problem Representation. Comput. Intell. 2021, 37, 931–963. [Google Scholar] [CrossRef] [Scilit]
- Kralev, V. An Analysis of a Recursive and an Iterative Algorithm for Generating Permutations Modified for Travelling Salesman Problem. Int. J. Adv. Sci. Eng. Inf. Technol. 2017, 7, 1685–1692. [Google Scholar] [CrossRef] [Scilit]
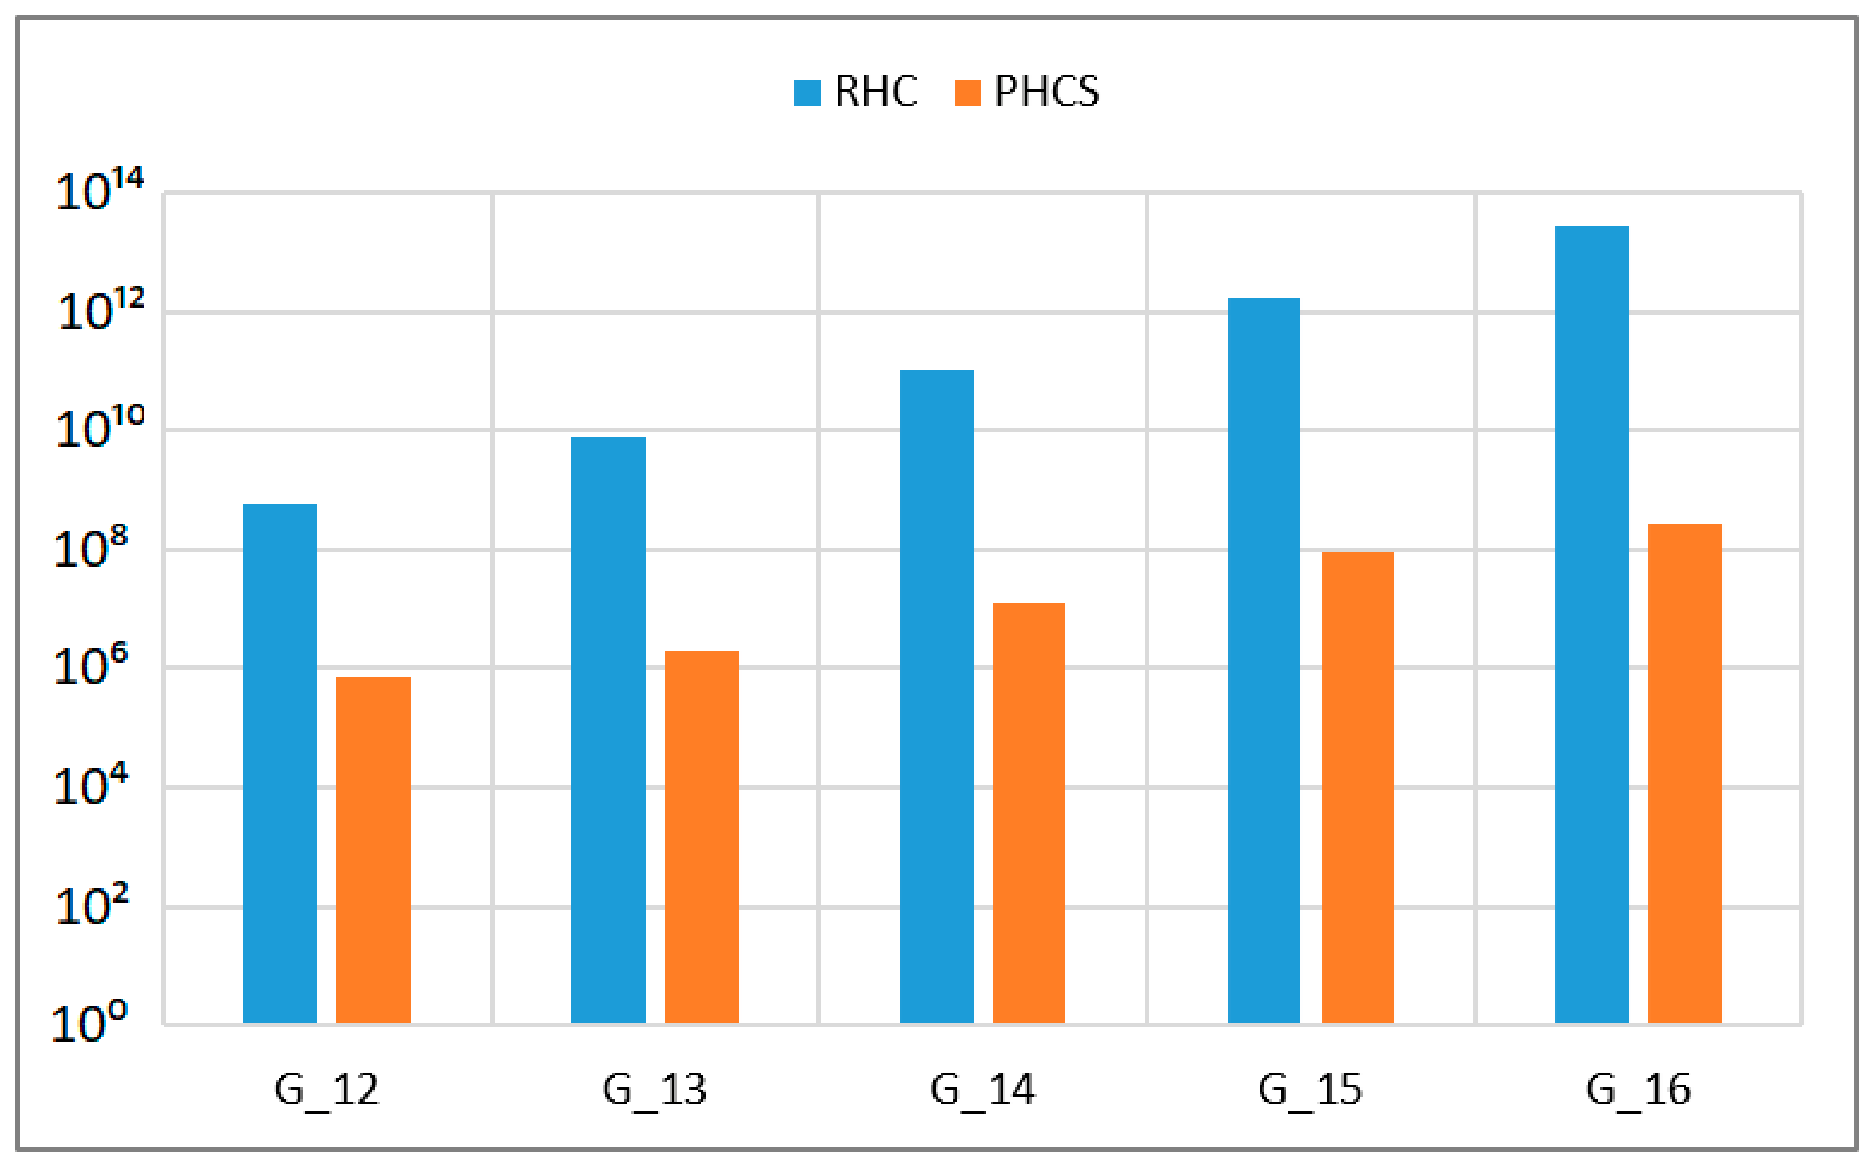

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.