


Abstract
This paper presents a short-term traction-load forecasting method that fuses optimization-driven dual-scale decomposition and multiscale information fusion (ODE-MMF) with TimeXer-Mamba to address non-stationary prediction difficulties caused by intermittent and volatile traction loads. A correlation analysis module is first constructed for adjacent feeding sections, where mutual information quantifies cross-arm load transfer induced by train operations and extracts key spatial features. In the ODE-MMF signal processing module, an improved whale migration algorithm searches for the optimal parameters of optimization-driven dual-scale decomposition, enabling multiscale decomposition of load features. Multiscale transfer entropy is then used to measure information flow among decomposed components, and highly redundant components are adaptively merged into complementary feature subsequences. In the TimeXer-Mamba prediction module, TimeXer enhances exogenous variables such as holidays, whereas Mamba captures long-range dependencies through the selective state-space model. A gated fusion mechanism integrates the two representations, after which the merged subsequences are predicted in parallel and reconstructed to obtain the final forecast. Experiments conducted on real-world traction-load data demonstrate that the proposed model consistently outperforms all evaluated baselines. Relative to the best-performing baseline, LSTM-Transformer, it achieves reductions of 9.61%, 9.32%, and 9.81% in mean absolute error, root mean square error, and mean absolute percentage error, respectively, while maintaining high computational efficiency and demonstrating strong potential for practical deployment in railway power supply systems.
1. Introduction
Under the “dual carbon” goals, railways serve as the backbone of green transportation, making the energy efficiency management of their traction power supply systems critically important [1]. The Chinese power grid requires railway sectors to provide accurate traction load forecasts and engage in electricity market transactions through direct power purchase schemes. Prediction errors exceeding 10% result in high-price settlements, which substantially increase operational costs [2]. However, traction load is influenced by multiple factors and exhibits strong non-stationarity and volatility, rendering it difficult to forecast accurately using conventional methods [3]. Therefore, there is a pressing need for a short-term forecasting approach capable of effectively capturing these complex load characteristics, in order to support low-carbon dispatching and refined management in railway systems.
The railway traction load profile exhibits marked nonlinearity and high volatility, rendering conventional prediction models based on statistical methods inadequate. To address this, signal decomposition techniques are commonly employed to decompose the original load into several stationary subsequences, thereby improving forecasting accuracy. For instance, an adaptive median filter (AMF) combined with empirical mode decomposition (EMD) has been used to decompose railway traction load signals, which are then fed into a temporal convolutional network (TCN) coupled with an improved temporal fusion transformer (TFT) for short-term forecasting [4]. Complete ensemble empirical mode decomposition with adaptive noise (CEEMDAN) has also been employed to decompose power load signals [5,6]. However, decomposition methods such as EMD and CEEMDAN can induce mode mixing. To address this issue, Li et al. optimized the variational mode decomposition (VMD) model using the orthogonal opposition-learning sparrow search algorithm (OOLSSA) and combined it with a long short-term memory (LSTM) network for load power forecasting [7]. An improved approach for electricity demand prediction integrates VMD with artificial neural networks, an attention-based bidirectional neural network, and an error correction method to forecast short-term power load demand [8]. Nevertheless, these single-stage decomposition methods often struggle to adequately separate the interwoven multiscale fluctuation characteristics inherent in the original signal. Consequently, an increasing number of studies have focused on secondary signal decomposition techniques. For integrated energy forecasting, the load series can first be decomposed using CEEMDAN, after which the most complex mode is identified via sample entropy (SE) and further decomposed using VMD to reduce non-stationarity [9]. Similarly, CEEMDAN and VMD have been combined for the secondary decomposition of solar power load signals, which are subsequently fed into a convolutional neural network-bidirectional long short-term memory (CNN-BiLSTM) model for solar load prediction [10]. However, VMD requires the pre-setting of parameters, specifically, the number of modes K and the penalty factor . ITD does not require the number of modes to be specified in advance; however, its baseline-control parameter can substantially affect the decomposition performance [11]. Nevertheless, ITD decomposition is also prone to mode mixing. Improved complete ensemble empirical mode decomposition with adaptive noise (ICEEMDAN) combined with robust local mean decomposition (RLMD) has been employed for the secondary decomposition of power load signals, effectively reducing noise interference and mitigating mode mixing [12]. Therefore, the integration of optimization algorithms with secondary decomposition techniques is a promising approach. However, secondary decomposition inevitably generates a large number of components, which subsequently impacts computational efficiency. To address this, refined composite multiscale weighted permutation entropy (RCMWPE) has been introduced to aggregate these components, thereby reducing computational load [13,14]. Similarly, SE has been used to measure the components of wind speed signals decomposed by CEEMDAN and merge them based on similarity principles [15]. Consequently, employing entropy-based methods to aggregate subsequences after signal decomposition proves to be an effective strategy. Based on the aforementioned research, an optimization-driven dual-scale decomposition and multiscale information fusion (ODE-MMF) traction load signal processing method is proposed. This method integrates an improved whale migration algorithm (IWMA)-optimized ITD-RLMD secondary decomposition technique, while employing multiscale transfer entropy (MTE) for component reconstruction. The ultimate objective is to achieve effective processing of railway traction load signals.
With the rapid advancement of machine learning and deep learning, single-model approaches for load forecasting have become increasingly inadequate. Consequently, hybrid multi-model prediction has emerged as a key research focus [16,17]. For instance, to address the challenge of forecasting wind power signals with complex characteristics, a hybrid model using multi-strategy mutation sand cat swarm optimization (SSCSO)-optimized VMD parameters and an adaptive boosting (AdaBoost)-enhanced CNN-BiLSTM architecture has been proposed to improve prediction accuracy and efficiency [18]. A hybrid forecasting framework combining Prophet, Bayesian optimization (BO), and extreme gradient boosting (XGBoost), termed Prophet-BO-XGBoost, has also been developed [19]. This framework utilizes BO to automatically tune the hyperparameters of XGBoost, while integrating the Prophet model to capture the temporal characteristics of the time series. Consequently, it enhances the accuracy and adaptability of the forecasting model under complex nonlinear conditions. In recent years, hybrid forecasting models predominantly constructed with Transformer and its variants have gained considerable attention. Compared to traditional algorithmically combined forecasting models, they demonstrate stronger competitiveness and have attracted significant research interest. A hybrid model combining LSTM and Transformer has been proposed for multi-step-ahead power load forecasting under multi-dimensional constraints such as geographical location and user behavior [20]. By integrating LSTM’s capability for capturing temporal dependencies with Transformer’s strength in understanding global context, the model achieves more accurate and efficient forecasting. A short-term forecasting model combining Transformer, bidirectional long short-term memory (BiLSTM), and patch embedding, termed Transformer-BiLSTM-Patch, has also been introduced [21]. This model innovatively employs a patch embedding technique, elevating attention computation from traditional point-to-point interaction to segment-to-segment interaction, thereby more effectively capturing local trends. Furthermore, the model removes the masking mechanism in the decoding stage to fully utilize the entire sequence information and incorporates a BiLSTM network to enhance the decoder’s ability to mine temporal features. This approach significantly improves the Transformer model’s performance in tasks involving comprehensive load and renewable energy forecasting. However, the aforementioned Transformer-based hybrid models generally share certain limitations, such as relatively low training efficiency, high computational resource requirements, and potentially large inference delays in scenarios characterized by high volatility and stringent real-time demands. These shortcomings may pose challenges for their application in ultra-short-term railway traction load forecasting, which requires rapid response. TimeXer has been integrated with attention mechanisms to reduce computational complexity while enhancing forecasting accuracy through fine-grained handling of short-term fluctuations and exogenous variables [22,23]. However, the TimeXer model exhibits limitations in effectively capturing long-term dependencies, a shortcoming that the Mamba architecture is well suited to compensate for. For instance, Mamba has been employed to capture long-term dependencies in power load data [24]. Moreover, a channel-independent bidirectional gated Mamba (CIBG-Mamba) model has been proposed to independently process each data channel and introduce interactive recurrent mechanisms [25]. This design effectively enhances the model’s capability to capture long-term dependencies and complex cross-dimensional dynamics in multivariate time series data. Nevertheless, the aforementioned research, including studies on railway traction load forecasting, primarily focuses on predictions with longer intervals such as 5 or 15 min. There remains a scarcity of studies utilizing ultra-long datasets with a 1 s resolution for forecasting.
Based on the foregoing analysis, this paper focuses on the temporal characteristics of traction load at ultra-short time intervals and proposes a short-term forecasting method that integrates ODE-MMF with TimeXer-Mamba. The proposed method employs ODE-MMF to perform optimized secondary decomposition and reconstruction of traction load signals. TimeXer is well suited to modeling short-term fluctuations and interactions with exogenous variables but is less effective at capturing long-range dependencies, whereas Mamba efficiently models long sequences but does not explicitly emphasize exogenous-variable interactions or local abrupt changes; their combination therefore provides complementary representations of short-term dynamics and long-range dependence. Existing studies on traction-load forecasting mainly use 5 or 15 min intervals, and, to the best of our knowledge, no previous study has combined TimeXer and Mamba for 1 s traction-load forecasting; this complementary architecture for the ultra-short-term traction-load setting is therefore the principal novelty of this study. This approach maintains high forecasting accuracy while substantially enhancing computational efficiency, thus offering an effective solution for short-term load forecasting in traction power supply systems.
The main innovations and contributions of this study are outlined as follows:
- (1)
- An adaptive signal preprocessing method, ODE-MMF, is proposed to tackle the challenges of high non-stationarity and difficulties in long-sequence modeling inherent in traction load data. This work presents an organic integration of the IWMA, the dual-scale decomposition combining ITD and RLMD, and multiscale transfer entropy, thereby establishing a comprehensive framework for adaptive data preprocessing.
- (2)
- An independent analysis module for spatial correlation features of adjacent feeding sections is constructed. This module employs correlation analysis modeling to precisely quantify the cross-arm load transfer patterns induced by train operation. It outputs a dynamic spatial correlation matrix, which provides critical spatial feature inputs for the forecasting model, thereby achieving the decoupling and precise injection of spatiotemporal features.
- (3)
- A TimeXer-Mamba hybrid forecasting architecture is designed for the collaborative modeling of spatiotemporal exogenous variables and long-range dependencies. The TimeXer module employs a cross-attention mechanism to dynamically learn the influence weights of exogenous variables such as holidays. The Mamba module, based on the selective state-space model, efficiently captures long-range dependencies. Through a gated fusion mechanism, the spatial features output by the independent analysis module are dynamically integrated with the endogenous sequence. The introduction of the selective state-space model (Mamba) into the field of railway traction load forecasting overcomes the computational bottleneck and attention dilution issues associated with Transformer models in processing long sequences. This enables efficient and accurate modeling of the long-term evolution patterns of the load and the spatiotemporal correlations across power supply arms.
- (4)
- A novel traction load forecasting framework is established. This framework integrates three key modules—“spatial correlation analysis, multiscale decomposition and reconstruction, and hybrid deep forecasting”—into a cohesive, closed-loop prediction pipeline. Experimental results demonstrate that the proposed framework outperforms conventional methods across multiple evaluation metrics, thereby providing a framework for addressing complex spatiotemporally correlated time series forecasting problems.
The remainder of this paper is organized as follows. Section 2 elaborates on the decomposition and aggregation method for traction load data based on ODE-MMF. Section 3 elaborates on the design of the TimeXer-Mamba hybrid model. Section 4 presents the overall framework of the proposed traction load forecasting method. Section 5 provides a detailed analysis and comparison, demonstrating the advantages of ODE-MMF over other preprocessing methods, and further evaluates the forecasting performance of the proposed TimeXer-Mamba model against other models from multiple perspectives to validate its effectiveness. Section 6 concludes the study and outlines potential directions for future research.
2. Decomposition and Aggregation Method for Traction Load Data Based on ODE-MMF
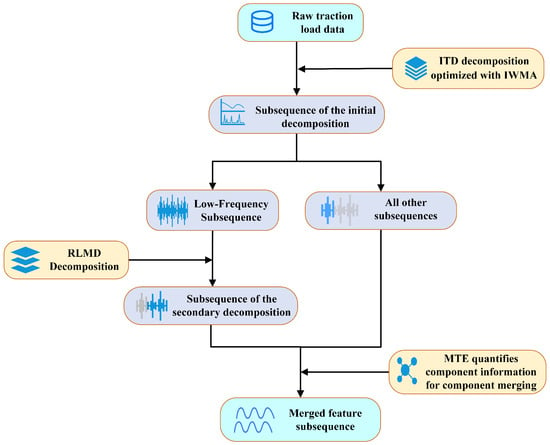
The optimization-driven dual-scale decomposition and multiscale information fusion (ODE-MMF) method proposed in this study is designed to systematically address the strong non-stationarity, high volatility, and multi-timescale coupling complexity exhibited by electrified railway traction loads. The core workflow is specifically designed for the characteristics of traction load signals. First, the IWMA is employed to globally optimize the decomposition parameters of ITD, constructing an optimization-driven dual-scale decomposition (OD2) core that adapts to the waveform characteristics of the current traction load. This step finely separates features at different scales within the load, such as traction/braking pulses, multi-locomotive superimposed oscillations, and fundamental trend components. Subsequently, to address the large number of potentially redundant components generated by the decomposition, MTE is introduced to quantify the dynamic information flow between components. Based on this, highly redundant components, such as harmonics from the same source or load fluctuations from correlated sections, are adaptively merged. This process forms feature subsequences with complementary information and clearer physical significance, laying a robust data foundation for subsequent effective forecasting. The specific procedure is illustrated in Figure 1.
Figure 1.
Flowchart of traction load data processing using the ODE-MMF method.
2.1. Dual-Scale Decomposition Based on OD2 for Traction Loads
2.1.1. Initial Decomposition Based on Optimized ITD
The traction-load sequence contains slowly varying components associated with overall traction demand, together with relatively rapid fluctuations caused by train operation and load switching. ITD adaptively separates these variations by constructing a baseline from local extrema and extracting proper rotation components (PRCs) at different characteristic time scales [11].
Consider an input signal at one ITD decomposition level. Let , where , denote its local extrema. The baseline-knot value is calculated from three consecutive extrema as
where is the baseline-control parameter. In the proposed method, IWMA is used to determine an optimized value of for the analyzed traction-load sequence.
Over , the baseline is constructed through an affine transformation of the input-signal amplitude:
The corresponding PRC is then obtained as
Let . At the i-th decomposition level, the current baseline is used as the input, yielding
where denotes the i-th PRC. The procedure is repeated until the stopping criterion is satisfied. The complete ITD representation is
where K is the number of extracted PRCs and is the final baseline. The PRCs are generally ordered from relatively high- to low-frequency content. The earlier PRCs mainly capture rapid short-term fluctuations, whereas the later PRCs represent variations over longer characteristic time scales. Because ITD does not produce strictly separated frequency bands, adjacent PRCs may contain overlapping frequency content. The final baseline retains the slowest-varying information and may still contain coupled low-frequency amplitude- and frequency-modulated fluctuations. It is therefore further decomposed using RLMD in the second stage.
2.1.2. Dual-Scale Decomposition Based on RLMD
The final ITD baseline may still contain coupled low-frequency amplitude- and frequency-modulated oscillations. Therefore, RLMD is applied in the second stage to further separate these variations into product functions (PFs). Compared with conventional LMD, RLMD employs mirror extension, adaptive envelope estimation, and a soft sifting stopping criterion to alleviate endpoint effects and mode mixing [26].
Let . To extract the p-th PF, the current residual is taken as the initial input:
During the j-th sifting iteration, the local mean function and local envelope function are estimated from adjacent extrema. In RLMD, mirror extension is used at the boundaries, and the moving-average subset size for envelope estimation is determined adaptively. The local mean is first removed:
after which the resulting signal is demodulated by the local envelope:
The sifting process is repeated until the soft stopping criterion is satisfied. If denotes the resulting number of iterations, the amplitude envelope and the p-th product function are obtained as
Here, describes the amplitude-modulation information, while represents the normalized frequency-modulated component. After extracting , the residual is updated as
The procedure is repeated until the residual satisfies the prescribed stopping criterion. Consequently, the final ITD baseline is expressed as
where P is the number of extracted PFs and is the final RLMD residual. The PFs are generally extracted from relatively short to long characteristic time scales, whereas retains the remaining slowly varying information. Combining the two decomposition stages gives
2.1.3. Multiscale Analysis and Fusion Decision
The implementation details of the multiscale transfer-entropy analysis are specified as follows. The Kraskov–Stögbauer–Grassberger (KSG) estimator is adopted for nonparametric probability estimation, which is suitable for nonlinear load time series. The embedding dimension and time delay are set to and , respectively. The scale factor s is selected from 1 to 5, and the threshold is set to 1.5 times the mean value of the transfer-entropy matrix at each scale to identify significant information flow.
First, multiscale analysis is performed. The dynamics of the traction load exist at multiple time scales. Each component undergoes coarse-graining to obtain its series at scale s. Subsequently, the transfer entropy (TE) matrices for all component pairs are computed across all scales .
Next, a multiscale information flow network is constructed. For the matrix at each scale s, the threshold is used to identify significant directed information flows.
Finally, components corresponding to similar physical processes are merged. To avoid redundant directional notation, a single symmetric indicator is defined at each scale. Specifically, if both directed transfer-entropy values between components i and j exceed the scale-specific threshold ; otherwise, . The cross-scale information-flow consistency is then defined as the proportion of scales with significant bidirectional information flow:
A fusion threshold is set. If , components i and j are considered to have a strong mutual driving relationship across multiple time scales. They are then merged into a new feature subsequence , as follows:
This process iterates until no component pair satisfies the criteria. Ultimately, the high-dimensional component set C is reconstructed into a smaller set of feature subsequences , where each subsequence is highly self-consistent internally and the subsequences exhibit low information redundancy with each other. This provides a clear and low-redundancy input for the subsequent TimeXer-Mamba model, enabling efficient modeling tailored to the distinct physical characteristics of each subsequence.
2.2. Improved Whale Migration Algorithm for Optimizing ITD
The waveform of traction load varies dynamically with the operating schedule, rolling stock type, and line conditions. Fixed baseline control parameters in ITD struggle to achieve consistently good decomposition performance across diverse scenarios. The task of IWMA is to adaptively optimize the value for the historical load data of a current target traction power supply section or a specific time period. This enables the initial OD2 decomposition to optimally separate components with clear physical meanings.
The Whale Migration Algorithm (WMA) [27] uses a leader–follower migration mechanism to coordinate population exploration and exploitation. Let denote the position of the i-th whale at iteration t; in this study, it represents a candidate ITD baseline control parameter . After ranking the individuals in descending order of fitness, the first individuals are selected as leaders, with mean position . The leaders explore the search domain, while the remaining individuals follow the adjacent better-ranked whale and the leader group. The baseline WMA update is
where and are the lower and upper search bounds, are independent random vectors, ⊙ denotes the Hadamard product, and is the best position found up to iteration t. Although Equation (15) provides an effective migration framework, its migration amplitude is not explicitly adjusted with the iteration process, and its stochastic update may provide insufficient coordination between early exploration and late exploitation. Therefore, the IWMA proposed in this study introduces three improvements directly into the WMA update mechanism: a nonlinear migration factor, an adaptive inertia weight, and a Levy-flight perturbation.
2.2.1. Nonlinear Migration Factor
The original WMA does not explicitly adjust its migration amplitude according to the iteration number. To provide a smoother transition from broad migration in the early stage to refined exploitation in the later stage, a nonlinear migration factor is introduced as
where is the maximum number of iterations and controls the nonlinear decay. The normalized coefficient is applied to the follower-migration displacement in Equation (15). Thus, the original WMA displacement is retained at the beginning of the search, while the migration amplitude gradually decreases as the search approaches its final stage.
2.2.2. Adaptive Inertia Weight
To improve the transition of the leader group from global exploration to local exploitation, the adaptive inertia weight is defined as
where and are the prescribed maximum and minimum inertia weights, respectively. A relatively large weight preserves wider exploration during the early iterations, whereas a smaller weight promotes refinement around the leader group during the later iterations.
2.2.3. Levy-Flight Perturbation
To enhance the global exploration capability of WMA and reduce the risk of premature convergence, a Levy-flight perturbation is incorporated into the follower-migration mechanism. Each component of the Levy vector is generated using Mantegna’s rule:
where u and v are independent Gaussian random variables and is the Levy stability parameter. The symbol is used here to avoid confusion with the fusion threshold defined in Section 2.2.
For compactness, define the leader-attraction vector and the follower-guidance vector as
By incorporating the nonlinear migration factor, adaptive inertia weight, and Levy-flight perturbation into the baseline WMA, the final position-update equation of IWMA is expressed as
where is the Levy perturbation scale. The factor also attenuates the Levy step, allowing large jumps to increase population diversity in the early stage while avoiding excessive oscillation near convergence. Any component outside the feasible interval is projected back to the search domain:
where the minimum and maximum operations are performed componentwise. Because the fitness function used in this study is maximized, greedy selection retains the trial position only when it improves the fitness:
Based on the IWMA described above, the optimization of ITD is formulated as an adaptive search problem for the baseline control parameter. Let the feasible range of the ITD baseline control parameter be . Considering the fluctuation characteristics of traction loads, a fitness function is constructed to evaluate spectral sparsity, modal orthogonality, component complexity, and residual energy, as given by
where denotes the mean sparsity of the envelope spectrum of each PRC. represents the degree of orthogonality between the components, where a higher value indicates greater independence among the decomposed modes and reduced information overlap. is the permutation entropy (PE) averaged over all components, measuring the overall complexity. denotes the energy ratio of the final trend term to the total energy of the original signal. The fitness function (24) is maximized. All component terms are normalized before weighting, and the weights are non-negative and sum to one. and are treated as benefit indices, whereas and are treated as penalty indices. Therefore, maximizing the fitness function favors higher spectral sparsity and modal orthogonality, together with lower component complexity and residual energy.
The above evaluation and update operations are repeated until the maximum number of iterations is reached. The candidate parameter with the best global fitness is then taken as the optimized solution . This optimized parameter is used as the customized baseline control parameter for ITD decomposition of the corresponding dataset and is embedded into the first stage of the traction load OD2 preprocessing workflow.
Consequently, the starting point of the entire ODE-MMF framework is a decomposition result that is optimized for the specific characteristics of the current traction load data. This yields multiscale physical modes that are most effectively separated, thereby establishing a high-quality data foundation for the subsequent TimeXer-Mamba prediction.
3. TimeXer-Mamba Hybrid Model Design
Traction load sequences exhibit both localized abrupt changes and long-term trends. To jointly model these two types of patterns, this work proposes a TimeXer-Mamba hybrid predictor. Its core adopts a dual-branch parallel architecture: the TimeXer branch specializes in fusing multi-source exogenous variables and capturing local temporal patterns, while the Mamba branch, based on a selective state-space model (SSM), efficiently captures long-sequence dependencies.
Let the historical load sequence be denoted as X, and the set of exogenous variables (including adjacent feeding-section loads, holiday indicators, etc.) as . The model’s prediction target is the future load sequence for the next T steps, . Its computational flow can be formally defined by
where L represents the length of the input historical sequence. is the dimension of the input features. denotes the dimension of the exogenous variables, including factors such as holiday types and adjacent feeding-section loads. T indicates the forecast horizon. is the dimension of the output features. In this study, the model performs one-step-ahead forecasting, therefore, the input window length is set to , and the forecasting horizon is .
3.1. TimeXer Module: Exogenous Variable Enhancement and Local Perception Mechanism
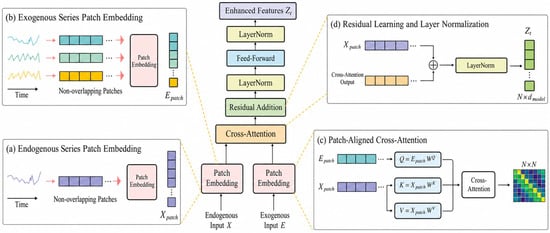
The core innovation of the TimeXer module lies in integrating exogenous variable embedding with local cross-attention, achieving deep interaction between external factors and the load sequence [28]. Its architectural diagram is shown in Figure 2.
Figure 2.
TimeXer architecture diagram.
3.1.1. Unified Embedding Representation for Multi-Source Variables
To handle heterogeneous exogenous variables, this module designs a unified embedding layer. Because L may not be divisible by the non-overlapping patch length P, replication padding is applied to the end of the input sequence by repeating its last observation until the padded length is divisible by P. Accordingly, the number of patches is . For the historical load sequence , the replication-padding and patching operations produce The resulting patches are projected into the embedding space as
where denotes the weight matrix, and denotes the bias vector broadcast across the N patch tokens.
The same replication-padding and patching operations are applied to the exogenous-variable sequence , yielding The exogenous patch embedding is then computed as
where denotes the weight matrix and denotes the bias vector broadcast across the N patch tokens. The same patch length and padding strategy are applied to X and E, ensuring that and contain the same number of temporally aligned tokens.
This step maps multi-source heterogeneous patterns into the same high-dimensional space, laying the foundation for subsequent cross-modal interaction.
3.1.2. Cross-Attention-Based Variable Interaction Modeling
To quantify the influence of exogenous variables on load dynamics, a cross-attention mechanism is introduced [29]. The query is derived from the exogenous patch tokens , whereas the key and value are derived from the endogenous load patch tokens . The cross-attention output is computed as
where , , and . Thus, , , , and the attention output belongs to . This mechanism dynamically captures the interactions between exogenous variables and historical load across different temporal patches.
For instance, load fluctuations in adjacent feeding sections during holidays may have a greater influence on the current load prediction.
3.1.3. Residual Learning and Layer Normalization
To maintain training stability and facilitate information flow, the cross-attention output is first combined with the endogenous patch representation through a residual connection:
The resulting representation is subsequently refined through a feed-forward network, followed by another residual connection and layer normalization:
The TimeXer module outputs the enhanced features , which incorporate information from the exogenous variables.
3.2. Mamba Module: Efficient Capture of Long-Range Dependencies
Traditional Transformer models face the bottleneck of quadratic computational complexity when processing long sequences. To overcome this limitation, the Mamba module, based on the latest selective state-space models, achieves effective modeling of long-range dependencies while maintaining linear computational complexity [30].
3.2.1. Selective SSM
Mamba generalizes the classical linear time-invariant state-space model (LTI-SSM) to a linear time-varying state-space model (LTV-SSM). The key enhancement lies in making the system parameters, namely, B controlling input influence, C controlling state output, and the discretization step size, functions of the input , thereby enabling selective response to input content. The state-space equations in continuous time are given by
To adapt the system for discrete-time sequence processing, the continuous-time system is discretized using the zero-order hold (ZOH) method, yielding the following discrete parameters [30]:
The corresponding discrete state equation and output equation are given by
where denotes the input vector at time step t. denotes the hidden state vector at time step t, with N being the state-space dimension. denotes the output vector at time step t. A represents the state transition matrix. The parameter denotes the selective input matrix, generated from the input via a linear layer . denotes the selective output matrix, generated from the input via a linear layer , enabling the model to selectively read information from the state based on the input. is the selective step-size parameter, controlling the degree of discretization. It is generated from the input via a linear layer followed by a Softplus activation function, ensuring a positive step size. D denotes the skip connection parameter, allowing the input to be directly passed to the output.
3.2.2. Parallel Scan and Efficient Computation
Although the state equations are recursive in nature, Mamba employs a parallel scan algorithm to convert the recursive computations into efficient parallel operations, significantly enhancing the processing speed for long sequences. Finally, the selective SSM output is modulated by the SiLU-activated signal from the parallel gating branch, followed by layer normalization, patch-wise average pooling, and linear projection:
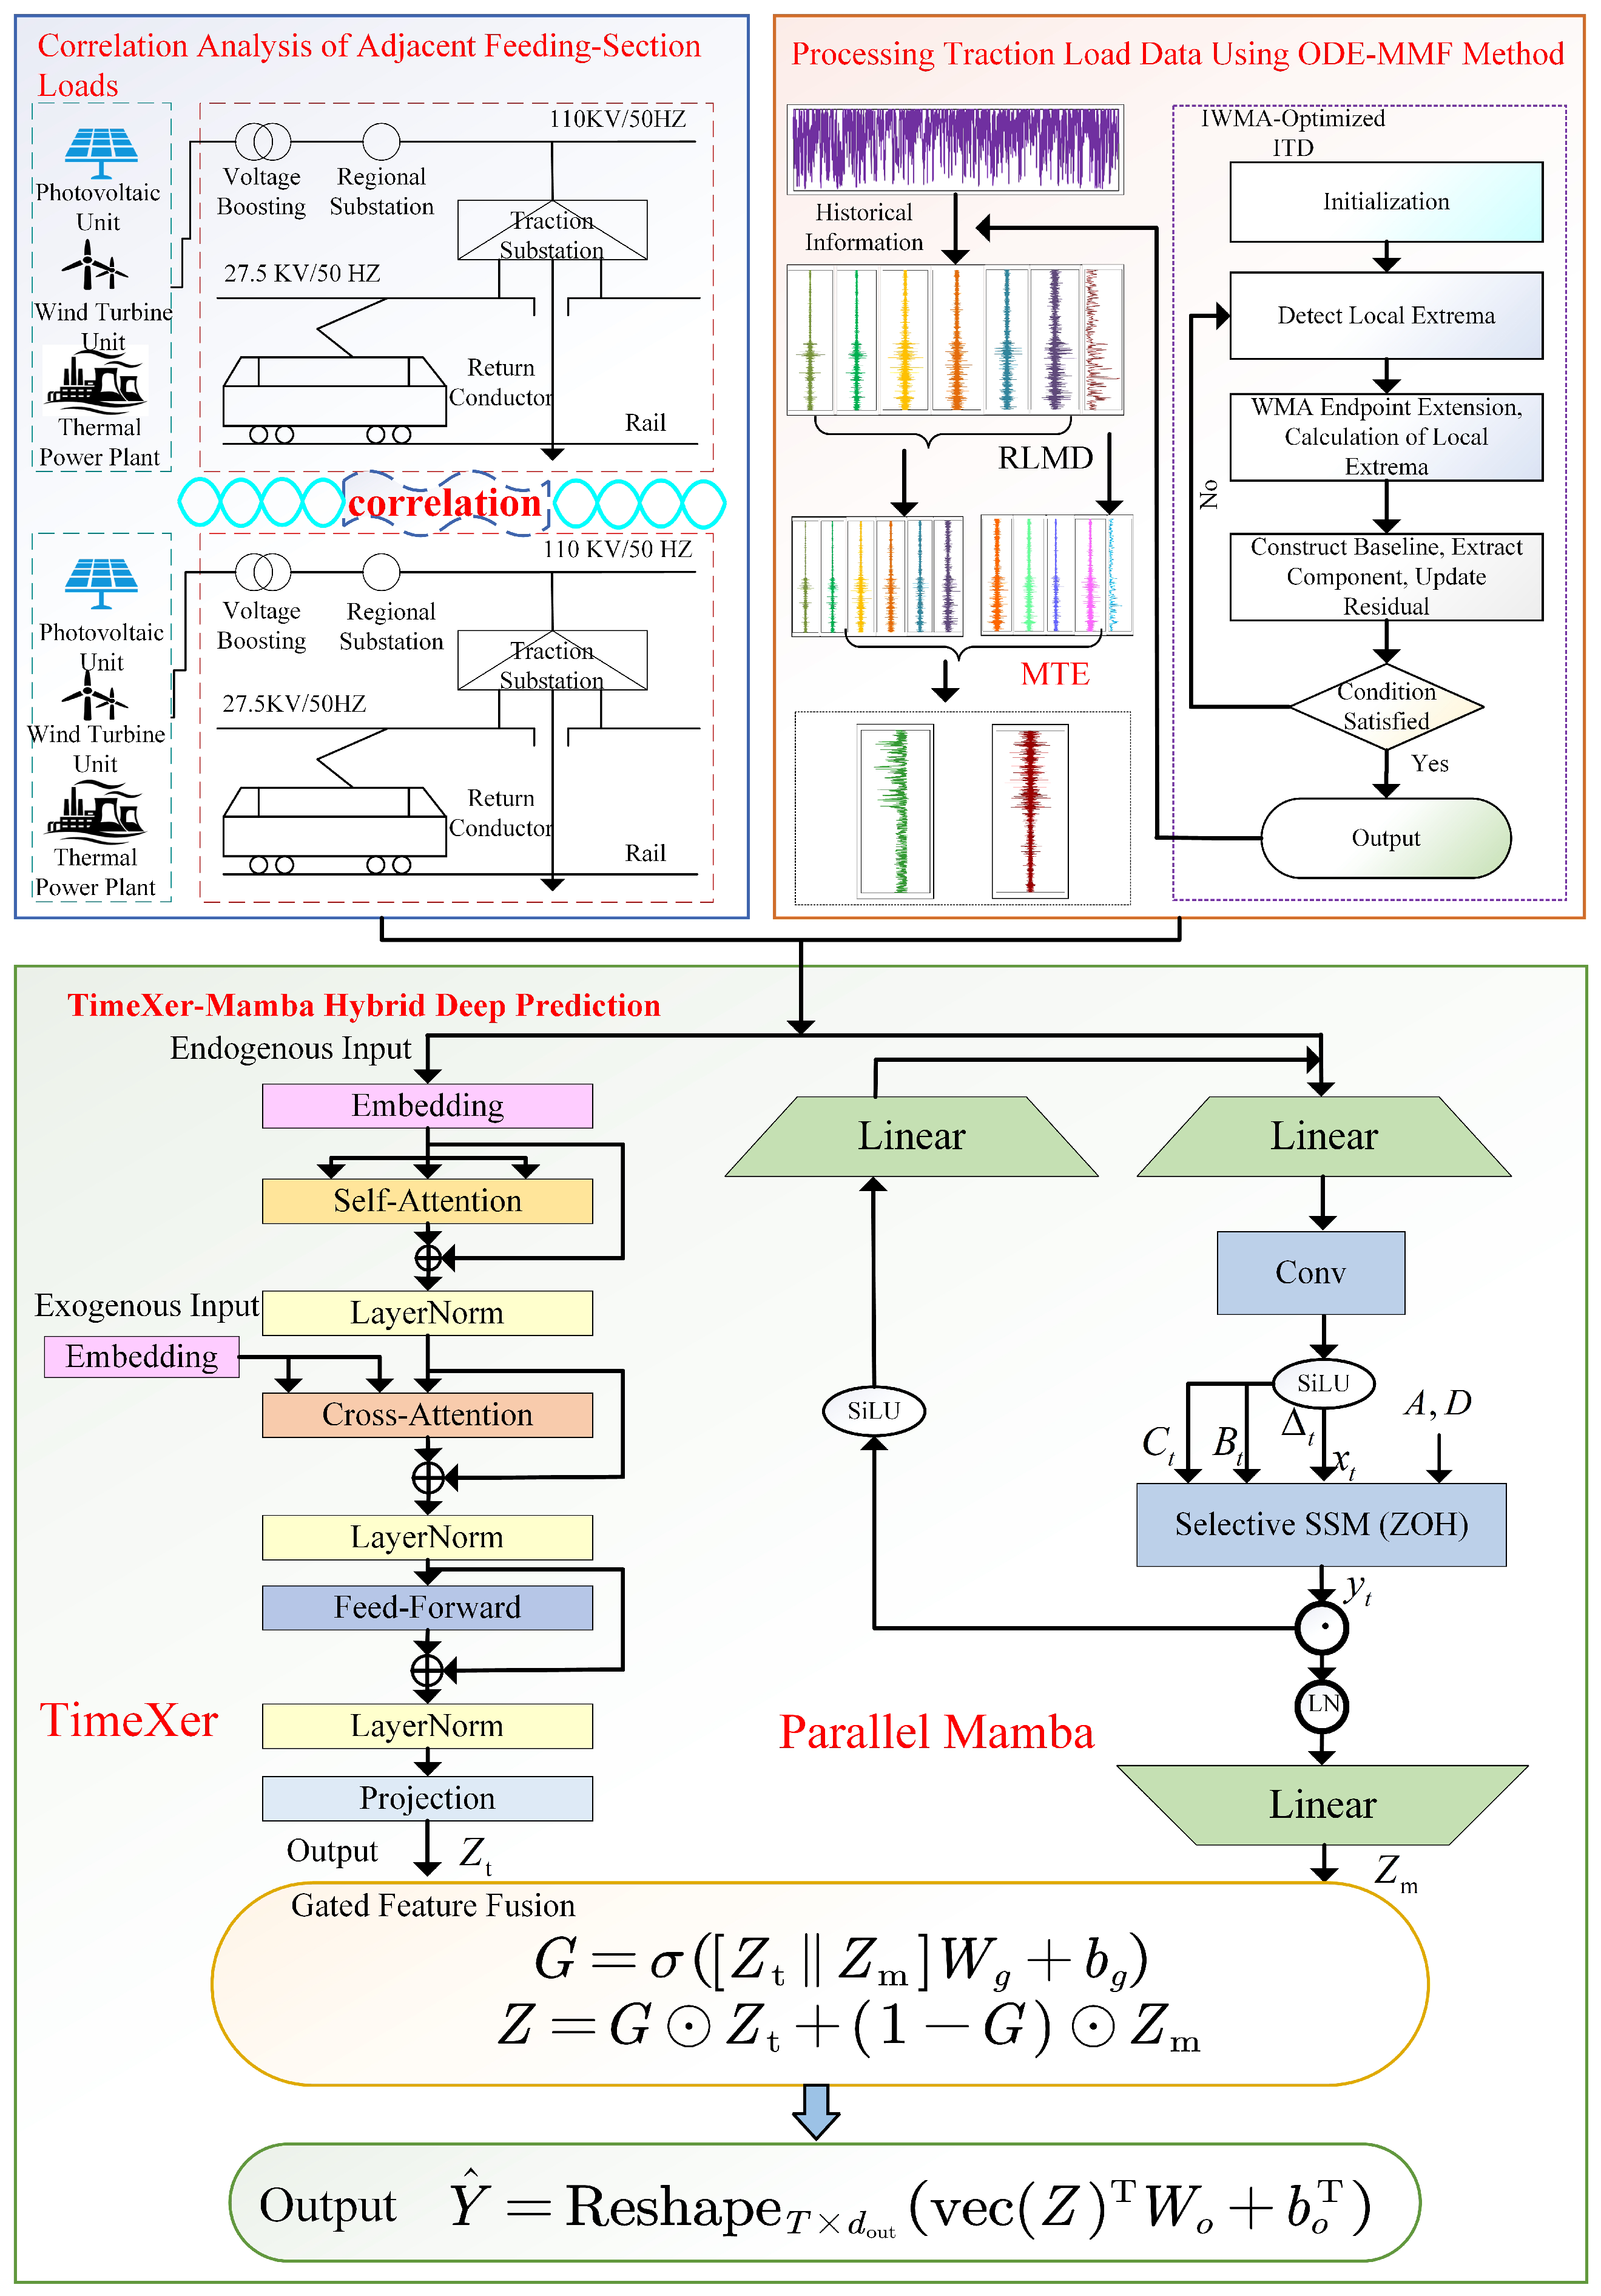
where denotes the signal generated by the parallel gating branch, and denotes patch-wise average pooling using the same patch length P as that employed in the TimeXer branch, with replication padding applied when necessary. This operation aligns the temporal dimensions of the two branch outputs. For clarity, the patch-wise pooling operation is omitted from Figure 3. denotes patch-wise average pooling using the same patch length P as that employed in the TimeXer branch, with replication padding applied when necessary. This operation aligns the temporal dimensions of the two branch outputs.
Figure 3.
Overall framework of traction load prediction.
3.3. Gated Feature Fusion and Output Prediction
The exogenously enhanced features output by the TimeXer branch and the long-range dependency features output by the Mamba branch differ in information granularity and focus. To integrate them adaptively, a gated fusion unit is designed.
The TimeXer output and the Mamba output have the same dimensions . The token-wise and feature-wise gate is defined as
where , is broadcast across the N patch tokens, and . The fused representation is computed as
Here, denotes the element-wise complementary gate. In this formulation, gate values close to one assign more weight to the TimeXer representation, while values close to zero assign more weight to the Mamba representation. For the displayed flattening prediction head, and . The fused representation Z is flattened and projected to the declared forecasting output ; in this study, .
4. Traction Load Prediction Framework
To address the challenges of predicting the non-stationarity arising from the intermittent and fluctuating nature of traction load, this paper constructs a three-stage prediction framework. The framework adopts a progressive design from feature extraction to prediction modeling. First, mutual information is used to analyze the spatial correlation of adjacent feeding sections, quantifying load interference characteristics. Then, the ODE-MMF signal processing module is employed to achieve multiscale decomposition and reconstruction of the load sequence, generating complementary feature subsequences. Finally, the TimeXer-Mamba hybrid prediction module integrates multi-source features to enable efficient modeling of complex spatiotemporal dynamics. The overall framework is illustrated in Figure 3, For compactness, , , and are denoted by , , and , respectively, in Figure 3. In contrast to these input-dependent parameters, A and D are input-independent parameters learned during training. Each module is described in detail below.
4.1. Spatial Correlation Analysis Module for Adjacent Feeding Sections
In traction power supply systems, the loads of adjacent feeding sections exhibit significant correlations due to factors such as train operation, energy feedback, and electrical coupling. To robustly capture their nonlinear dependency characteristics, a spatial correlation analysis module based on mutual information is designed. This module operates independently by calculating the mutual information between the load sequences of the target power supply section and each adjacent section, thereby quantifying their statistical dependency strength. A sliding window mechanism is employed to evaluate mutual information across different time scales, constructing a dynamic spatial correlation strength matrix. Based on this matrix, adjacent sections that exert a significant influence on prediction are selected, and a weighted spatial correlation feature vector is generated. With mutual information as the core metric, this method characterizes the spatial interference nature of traction loads, providing critical structured feature inputs for subsequent prediction.
4.2. ODE-MMF Signal Processing Module
To address the adverse effects of strong non-stationarity and multiscale mixing in raw load sequences on prediction accuracy, an ODE-MMF signal processing module is proposed. This module employs a two-phase strategy: first, it utilizes key parameters of the OD2 algorithm for automatic parameter optimization. OD2 combines the adaptiveness of ITD and the mode-decoupling capability of RLMD. The optimized parameters enable the generation of a set of well-separated decomposed components, each representing distinct physical processes. Subsequently, multiscale transfer entropy is introduced as a measure of information flow. Components with similar information flow patterns are adaptively merged. Ultimately, the module outputs a refined set of reconstructed subsequences characterized by a reduced number, high internal autocorrelation, and low mutual redundancy, providing high-quality multiscale feature inputs for the prediction model.
4.3. TimeXer-Mamba Hybrid Prediction Module
This module consists of the TimeXer exogenous-enhanced encoder, the Mamba long-sequence modeler, and the gated fusion decoder, designed to collaboratively model multiscale temporal features, spatial correlation features, and exogenous variables. The TimeXer encoder projects multi-source features into a high-dimensional space via an embedding layer and dynamically evaluates the influence weights of exogenous variables on the target sequence using a cross-attention mechanism, generating a context-enhanced temporal representation. The Mamba modeler is constructed based on a selective state-space model, which efficiently captures long-range dependencies through an input-dependent selective mechanism. Its linear computational complexity avoids the computational bottleneck of Transformer models when handling long sequences. The gated fusion decoder adaptively fuses the contextual features from TimeXer and the long-term dependency features from Mamba via a learnable gating unit. The fusion result is then linearly projected to obtain the predicted values for each subsequence, which are aggregated to produce the final load prediction. This architecture achieves an organic integration of deep exogenous variable interaction and efficient long-sequence modeling.
5. Case Study Analysis
To validate the effectiveness and superiority of the proposed ODE-MMF and TimeXer-Mamba forecasting framework, experiments are carried out using measured feeder power data from a railway traction substation. The analysis covers dataset construction, evaluation metrics, preprocessing methods, prediction models, ablation variants, and computational efficiency, thereby providing a comprehensive assessment under consistent training and testing conditions.
5.1. Data Description and Experimental Settings
The dataset consists of 63 days of feeder-power time-series data measured at a high-speed railway traction substation from 16 July to 16 September 2024, with a sampling interval of 1 s. At this resolution, a complete 24 h day contains 24 × 3600 = 86,400 samples. Because no regular trains operate during the daily maintenance window from 22:00 to 07:00, only the continuous operating period from 07:00 to 22:00 is retained, resulting in 15 × 3600 = 54,000 samples per operating day. The retained multi-day data are chronologically divided into training, validation, and test sets in a ratio of 6:3:1. The synchronized load power of the adjacent feeding sections and the date-type code (0 for weekdays, 1 for weekends, and 2 for statutory holidays) are incorporated as exogenous variables. A sliding window containing historical time steps is used to predict the next single time step ().
The experiments are conducted on a workstation equipped with an Intel Core i9-13900K CPU, an NVIDIA GeForce RTX 4090 GPU, and 64 GB of RAM. The software environment comprises Ubuntu 22.04.4 LTS, Python 3.9.18, PyTorch 2.0.1, and CUDA 11.8. Min–max normalization is applied to the data, and the model is trained using the AdamW optimizer with an initial learning rate of , a batch size of 64, and a maximum of 100 epochs. An early-stopping strategy is adopted: training is terminated if the validation loss does not decrease for 10 consecutive epochs, and the model with the lowest validation loss is retained. The hidden dimension and Mamba state dimension are determined through grid search over and , respectively. Unless otherwise stated, each experiment was independently repeated 10 times under the same experimental settings, and the mean value across the 10 runs is reported for each evaluation metric.
5.2. Evaluation Metrics
Model performance is assessed using root mean square error (RMSE), mean absolute error (MAE), mean absolute percentage error (MAPE), and the coefficient of determination (R2), as defined in Equations (37)–(40). Lower RMSE, MAE, and MAPE values indicate smaller prediction errors, whereas an value closer to 1 indicates a better fit to the measured load sequence.
where n denotes the total number of test samples, is the measured traction load, is the predicted traction load, and is the mean of the measured values in the evaluated test set. To avoid division by zero and unstable percentage errors, test samples satisfying were excluded only from the MAPE calculation, where and denotes the number of retained test samples satisfying . MAPE was calculated after inverse normalization on the original traction-load scale.
5.3. Comparison with Other Data Processing Methods
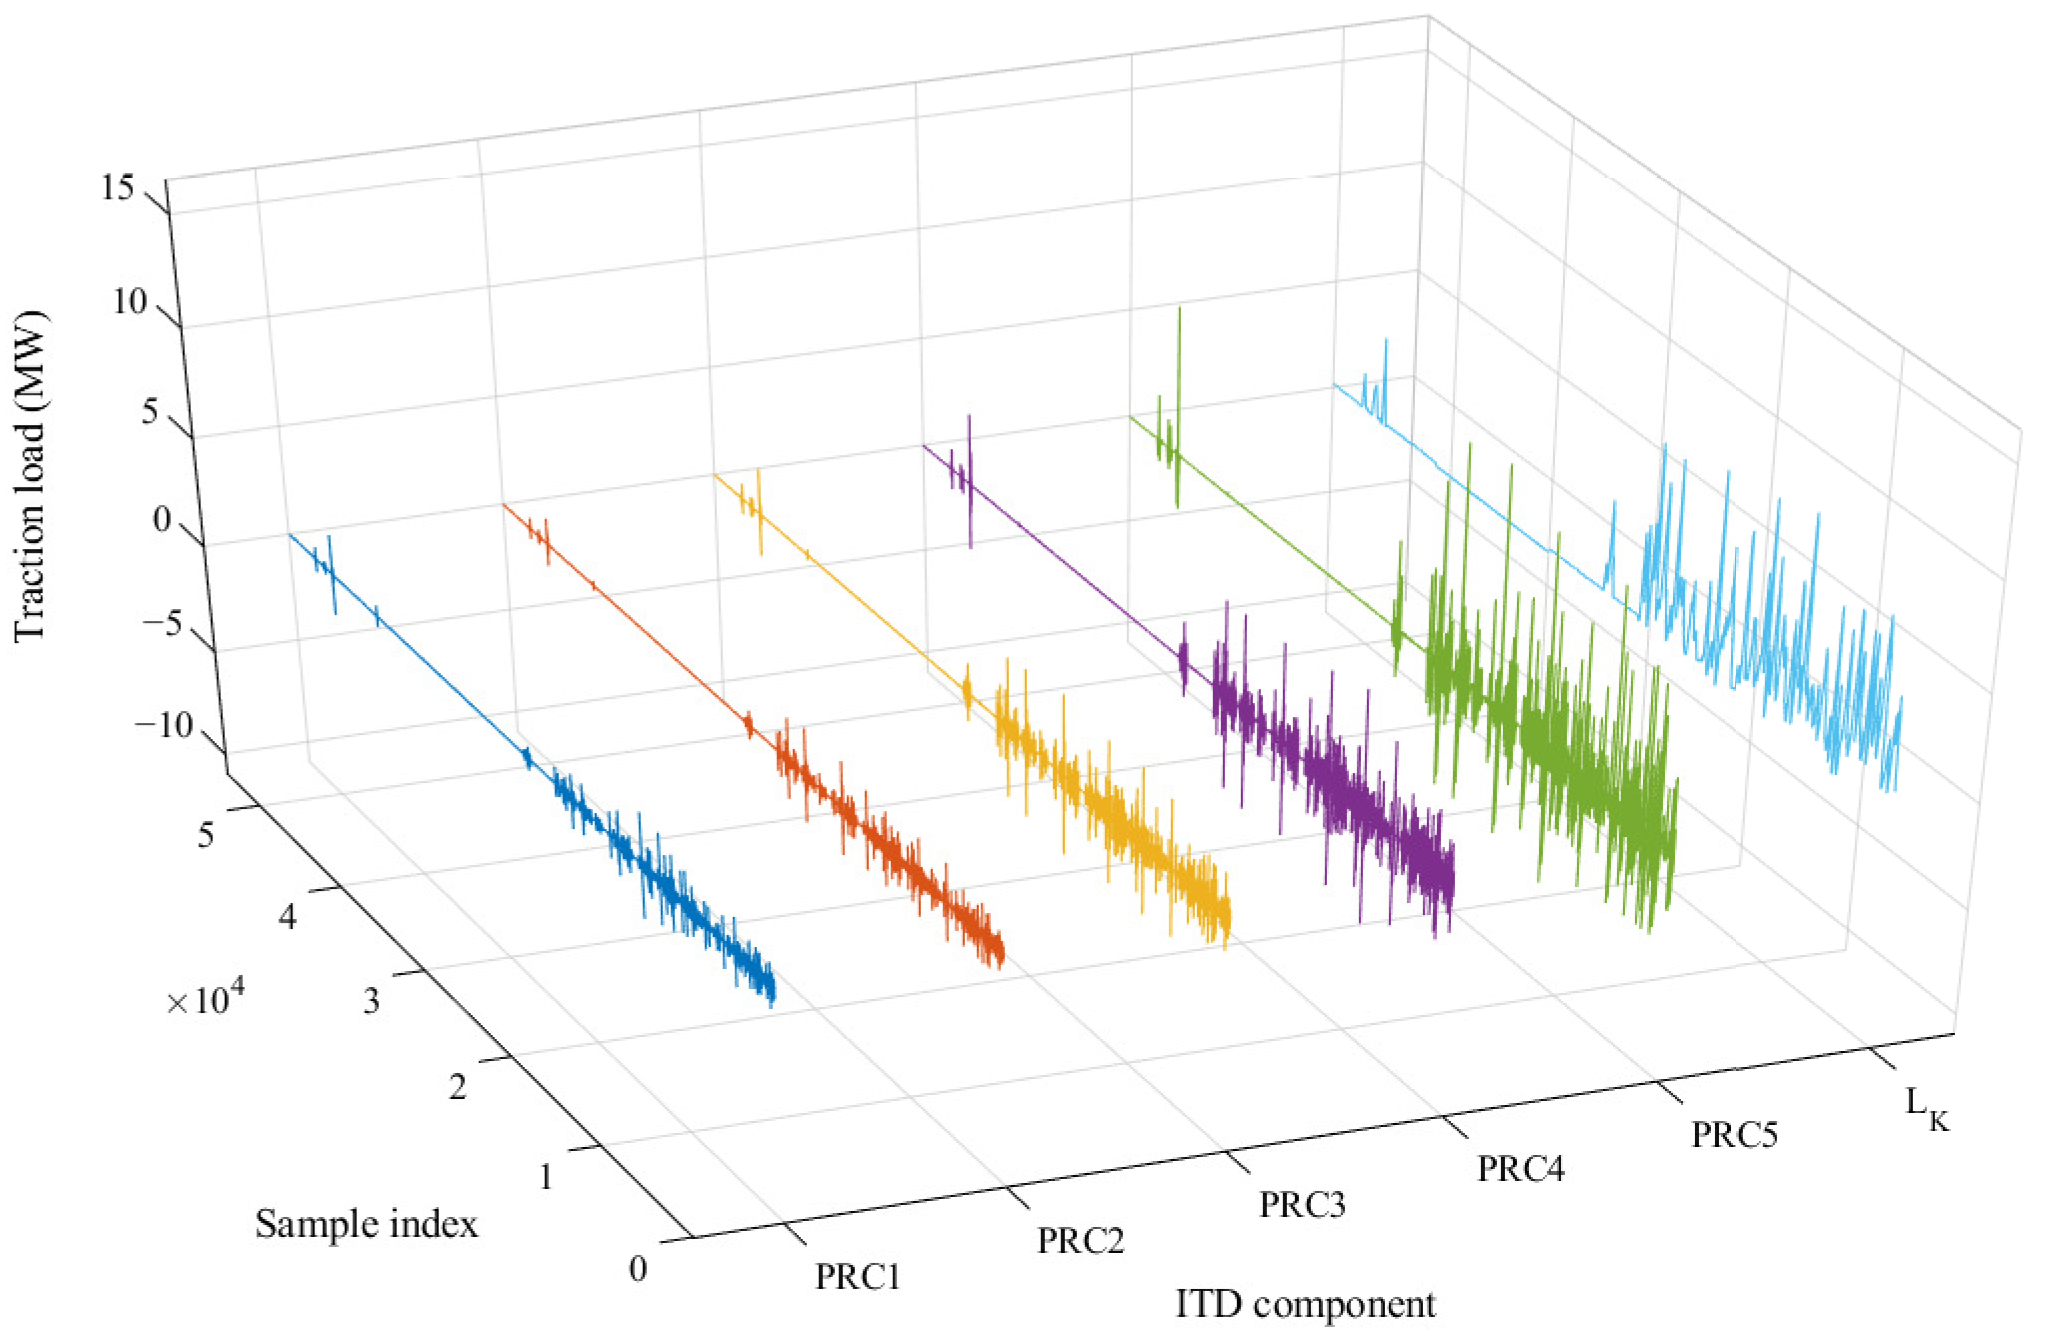
The ODE-MMF preprocessing method employs a two-stage decomposition strategy to separate traction-load variations at different characteristic time scales. In the first stage, IWMA is used to optimize the ITD baseline-control parameter , improving the adaptability of the decomposition to the local temporal characteristics of the measured traction-load sequence. As shown in Figure 4, the ITD component axis displays five proper rotation components, denoted by –, together with the final baseline . The sample-index axis represents the chronological order of the observations, while the vertical axis represents the component amplitude in MW.
Figure 4.
IWMA-optimized ITD decomposition of the traction-load sequence.
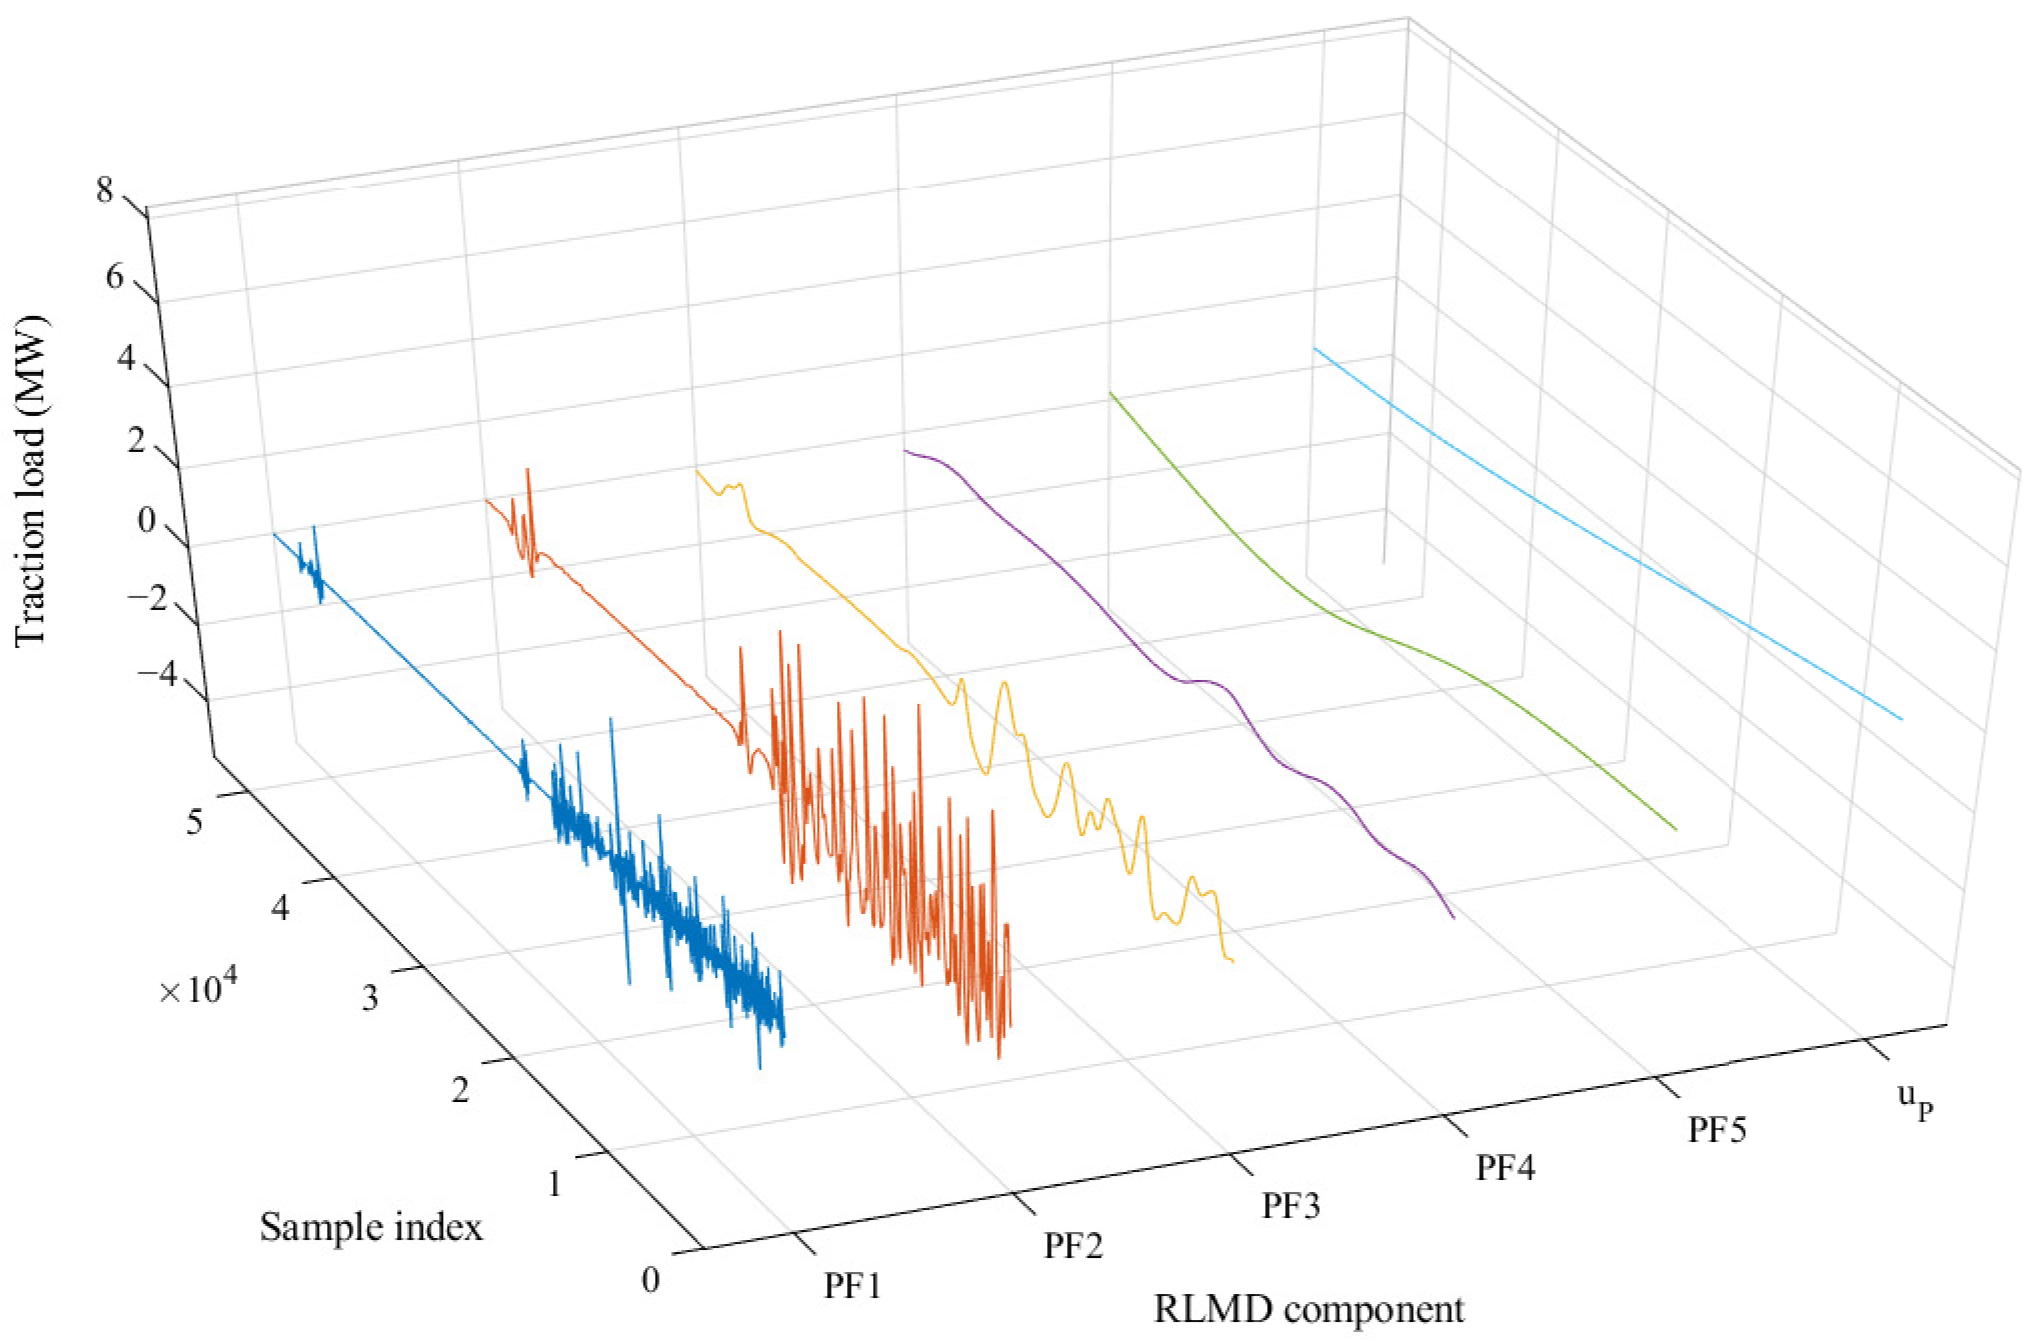
The PRCs are generally ordered from relatively high- to low-frequency content, corresponding to progressively longer characteristic time scales. Thus, the earlier PRCs mainly represent rapid short-term fluctuations, whereas the later PRCs describe variations over longer time scales. Because ITD does not produce strictly separated frequency bands, adjacent PRCs may contain overlapping frequency content. The final baseline retains the slowest-varying information that is not further separated during the initial ITD stage.
Because may still contain coupled low-frequency amplitude- and frequency-modulated variations, it is further decomposed using RLMD in the second stage. As shown in Figure 5, the RLMD component axis displays five product functions, denoted by –, together with the final residual . The PFs are generally ordered from relatively short to long characteristic time scales, whereas represents the remaining slowly varying residual. This secondary decomposition provides a more refined representation of the low-frequency temporal characteristics originally contained in .
Figure 5.
RLMD decomposition of the final ITD baseline.
After parameter optimization and the two-stage decomposition, the resulting multiscale component set comprises –, –, and . These components are subsequently processed by the multiscale transfer entropy (MTE)-based fusion procedure, which identifies and merges components containing related temporal information before traction-load forecasting.
To evaluate the performance of the proposed preprocessing strategy, several data-processing schemes are compared using the same dataset and the same TimeXer-Mamba predictor. The compared schemes include the raw sequence without decomposition, ITD decomposition, RLMD decomposition, ITD-RLMD secondary decomposition without MTE fusion, and the complete ODE-MMF preprocessing method. The averaged results are reported in Table 1.
Table 1.
Comparison of different signal decomposition preprocessing methods.
The raw sequence gives the largest prediction errors, with an MAE of 0.1160 MW, an RMSE of 0.1612 MW, and a MAPE of 8.74%. Both single-stage decomposition methods reduce these errors, indicating that separating part of the non-stationary fluctuation structure is beneficial for subsequent forecasting. The ITD-RLMD scheme further lowers the error levels relative to either ITD or RLMD alone, which shows the clear advantage of secondary decomposition for traction loads containing coupled fluctuations at multiple scales.
The complete ODE-MMF preprocessing obtains the lowest error values in Table 1, with an MAE of 0.0743 MW, an RMSE of 0.1109 MW, a MAPE of 5.61%, and an of 0.949. Compared with ITD-RLMD without MTE fusion, the additional fusion step further reduces the prediction errors. This result supports the effectiveness of MTE-based component aggregation, which suppresses redundant subsequences before prediction and provides a more compact input representation for the forecasting model.
To further verify the contribution of spatial correlation, an additional ablation experiment was conducted using three input settings: without feeding-section load data, with one adjacent feeding section, and with two adjacent feeding sections. The results are presented in Table 2.
Table 2.
Performance comparison of different spatial-correlation settings.
As shown in Table 2, the setting without adjacent feeding section produces the largest prediction errors. Incorporating one adjacent feeding section improves all four evaluation metrics, while using two adjacent feeding sections achieves the best overall performance, with the lowest MAE, RMSE, and MAPE and the highest . The progressive improvement from zero to one and then two adjacent feeding sections demonstrates that adjacent traction-load information provides complementary spatial information for load forecasting.
To further evaluate the model’s ability to capture long-range dependencies, additional experiments were conducted using input-window lengths of 100, 500, and 1000 time steps. The results are presented in Table 3.
Table 3.
Performance comparison under different input-window lengths.
As shown in Table 3, forecasting performance improves consistently as the input-window length increases. The 1000-step setting achieves the best performance, with the lowest MAE, RMSE, and MAPE and the highest . Although the overall improvements are moderate, the absence of performance degradation as the input window expands from 30 to 1000 time steps indicates that the proposed model can effectively utilize longer historical information and capture long-range temporal dependencies. Given the modest gains obtained with longer input windows, was retained as the default setting to balance forecasting accuracy and computational efficiency across all main experiments.
5.4. Comparison of TimeXer-Mamba with Other Prediction Models
To further verify the forecasting performance of TimeXer-Mamba, its performance is compared with that of representative time-series forecasting models using the same ODE-MMF-preprocessed data. The baselines include recurrent models, namely, LSTM and gated recurrent unit (GRU); attention-based models, namely, Transformer and Informer; and hybrid models, namely, LSTM-Transformer and CNN-BiLSTM. To ensure a fair comparison, all models use the same training, validation, and test sets, and their model-specific hyperparameters are selected through grid search. The model-specific parameter settings selected for the comparative experiments are reported in Table 4, while the corresponding forecasting results are summarized in Table 5.
Table 4.
Model-specific parameter settings of the compared models.
Table 5.
Performance comparison of different forecasting models.
As shown in Table 5, TimeXer-Mamba achieves the lowest MAE (0.0743 MW), RMSE (0.1109 MW), and MAPE (5.61%), together with the highest (0.949), demonstrating an effective improvement over the baseline models. Among the baselines, the hybrid models perform better than the single-architecture models, with LSTM-Transformer providing the closest result to the proposed model. This pattern indicates that the combined modeling of local variations and longer temporal dependencies is important for the present traction-load sequence.
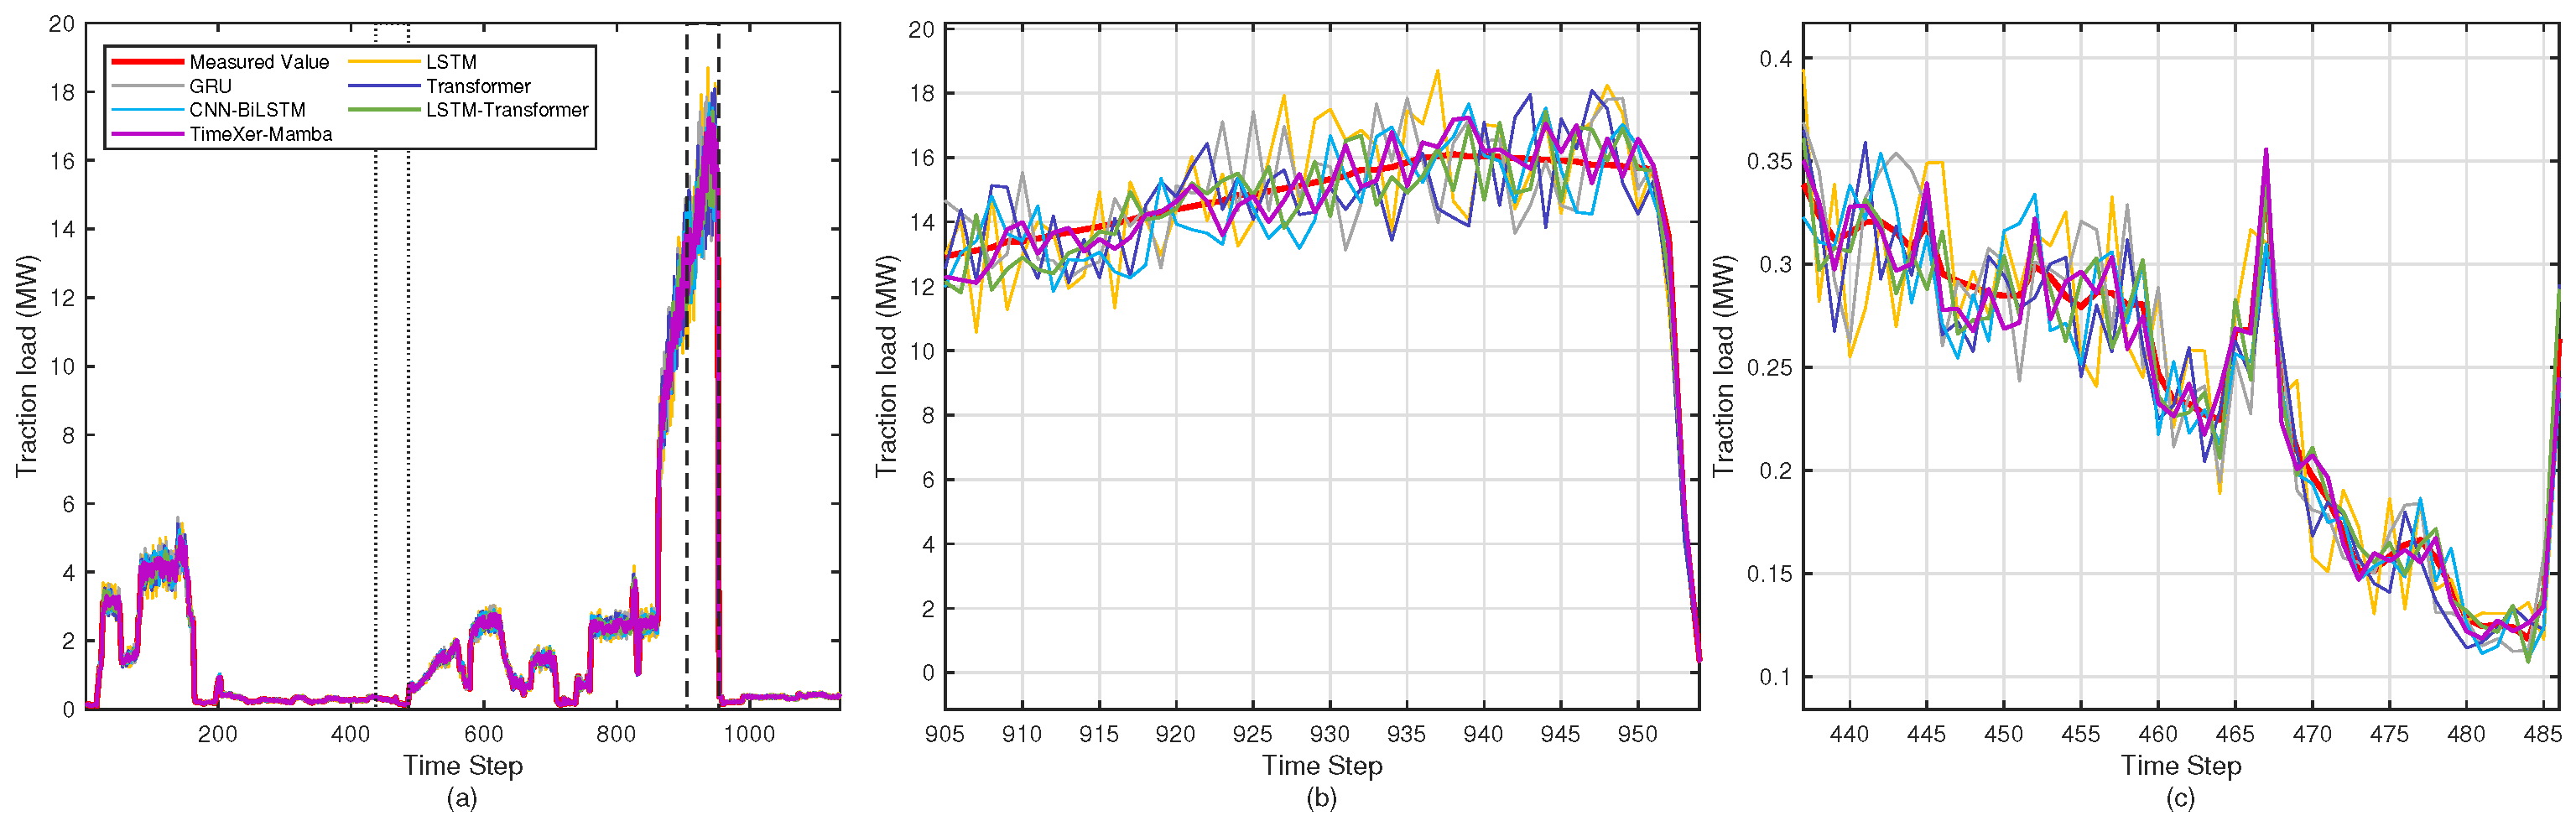
The prediction curves in Figure 6 provide a visual comparison between the measured load and the model outputs. Figure 6a provides an overview of the prediction results. Figure 6b and Figure 6c enlarge the high-ramping and low-load intervals, respectively. To avoid subjective selection, these intervals were determined exclusively from the measured-load sequence using the maximum accumulated absolute first-order difference and the minimum moving-average load, respectively.
Figure 6.
(a) Comparison of measured and predicted traction loads: (a) overall prediction results, with the vertical dashed and dotted lines indicating the intervals enlarged in panels (b) and (c), respectively; (b) High-ramping window. (c) Low-load window.
The joint evidence from Table 5 and Figure 6 shows that model differences are most apparent during rapid transitions and high-load ramping intervals. In these regions, TimeXer-Mamba follows the measured trajectory more closely than the other models, whereas the recurrent and attention-based baselines exhibit larger amplitude deviations. The enlarged views in Figure 6b,c further demonstrate the prediction differences under high-ramping and low-load conditions. Compared with the second-best LSTM-Transformer model, TimeXer-Mamba reduces MAE, RMSE, and MAPE by 9.61%, 9.32%, and 9.81%, respectively, while increasing by 1.2%, further validating the superior forecasting performance of the proposed model.
The performance advantage is closely related to the structure of the proposed model. The Mamba branch represents long-range temporal evolution with linear computational complexity, while the TimeXer branch incorporates exogenous variables through cross-attention. The gated fusion module combines these two representations according to the current input. As a result, the model can use historical load evolution and external driving information within the same prediction window, which is reflected in the lower errors in Table 5 and the closer curve alignment in Figure 6.
5.5. Ablation Study Comparison
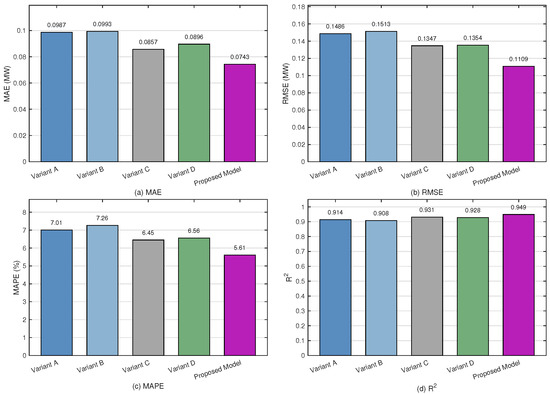
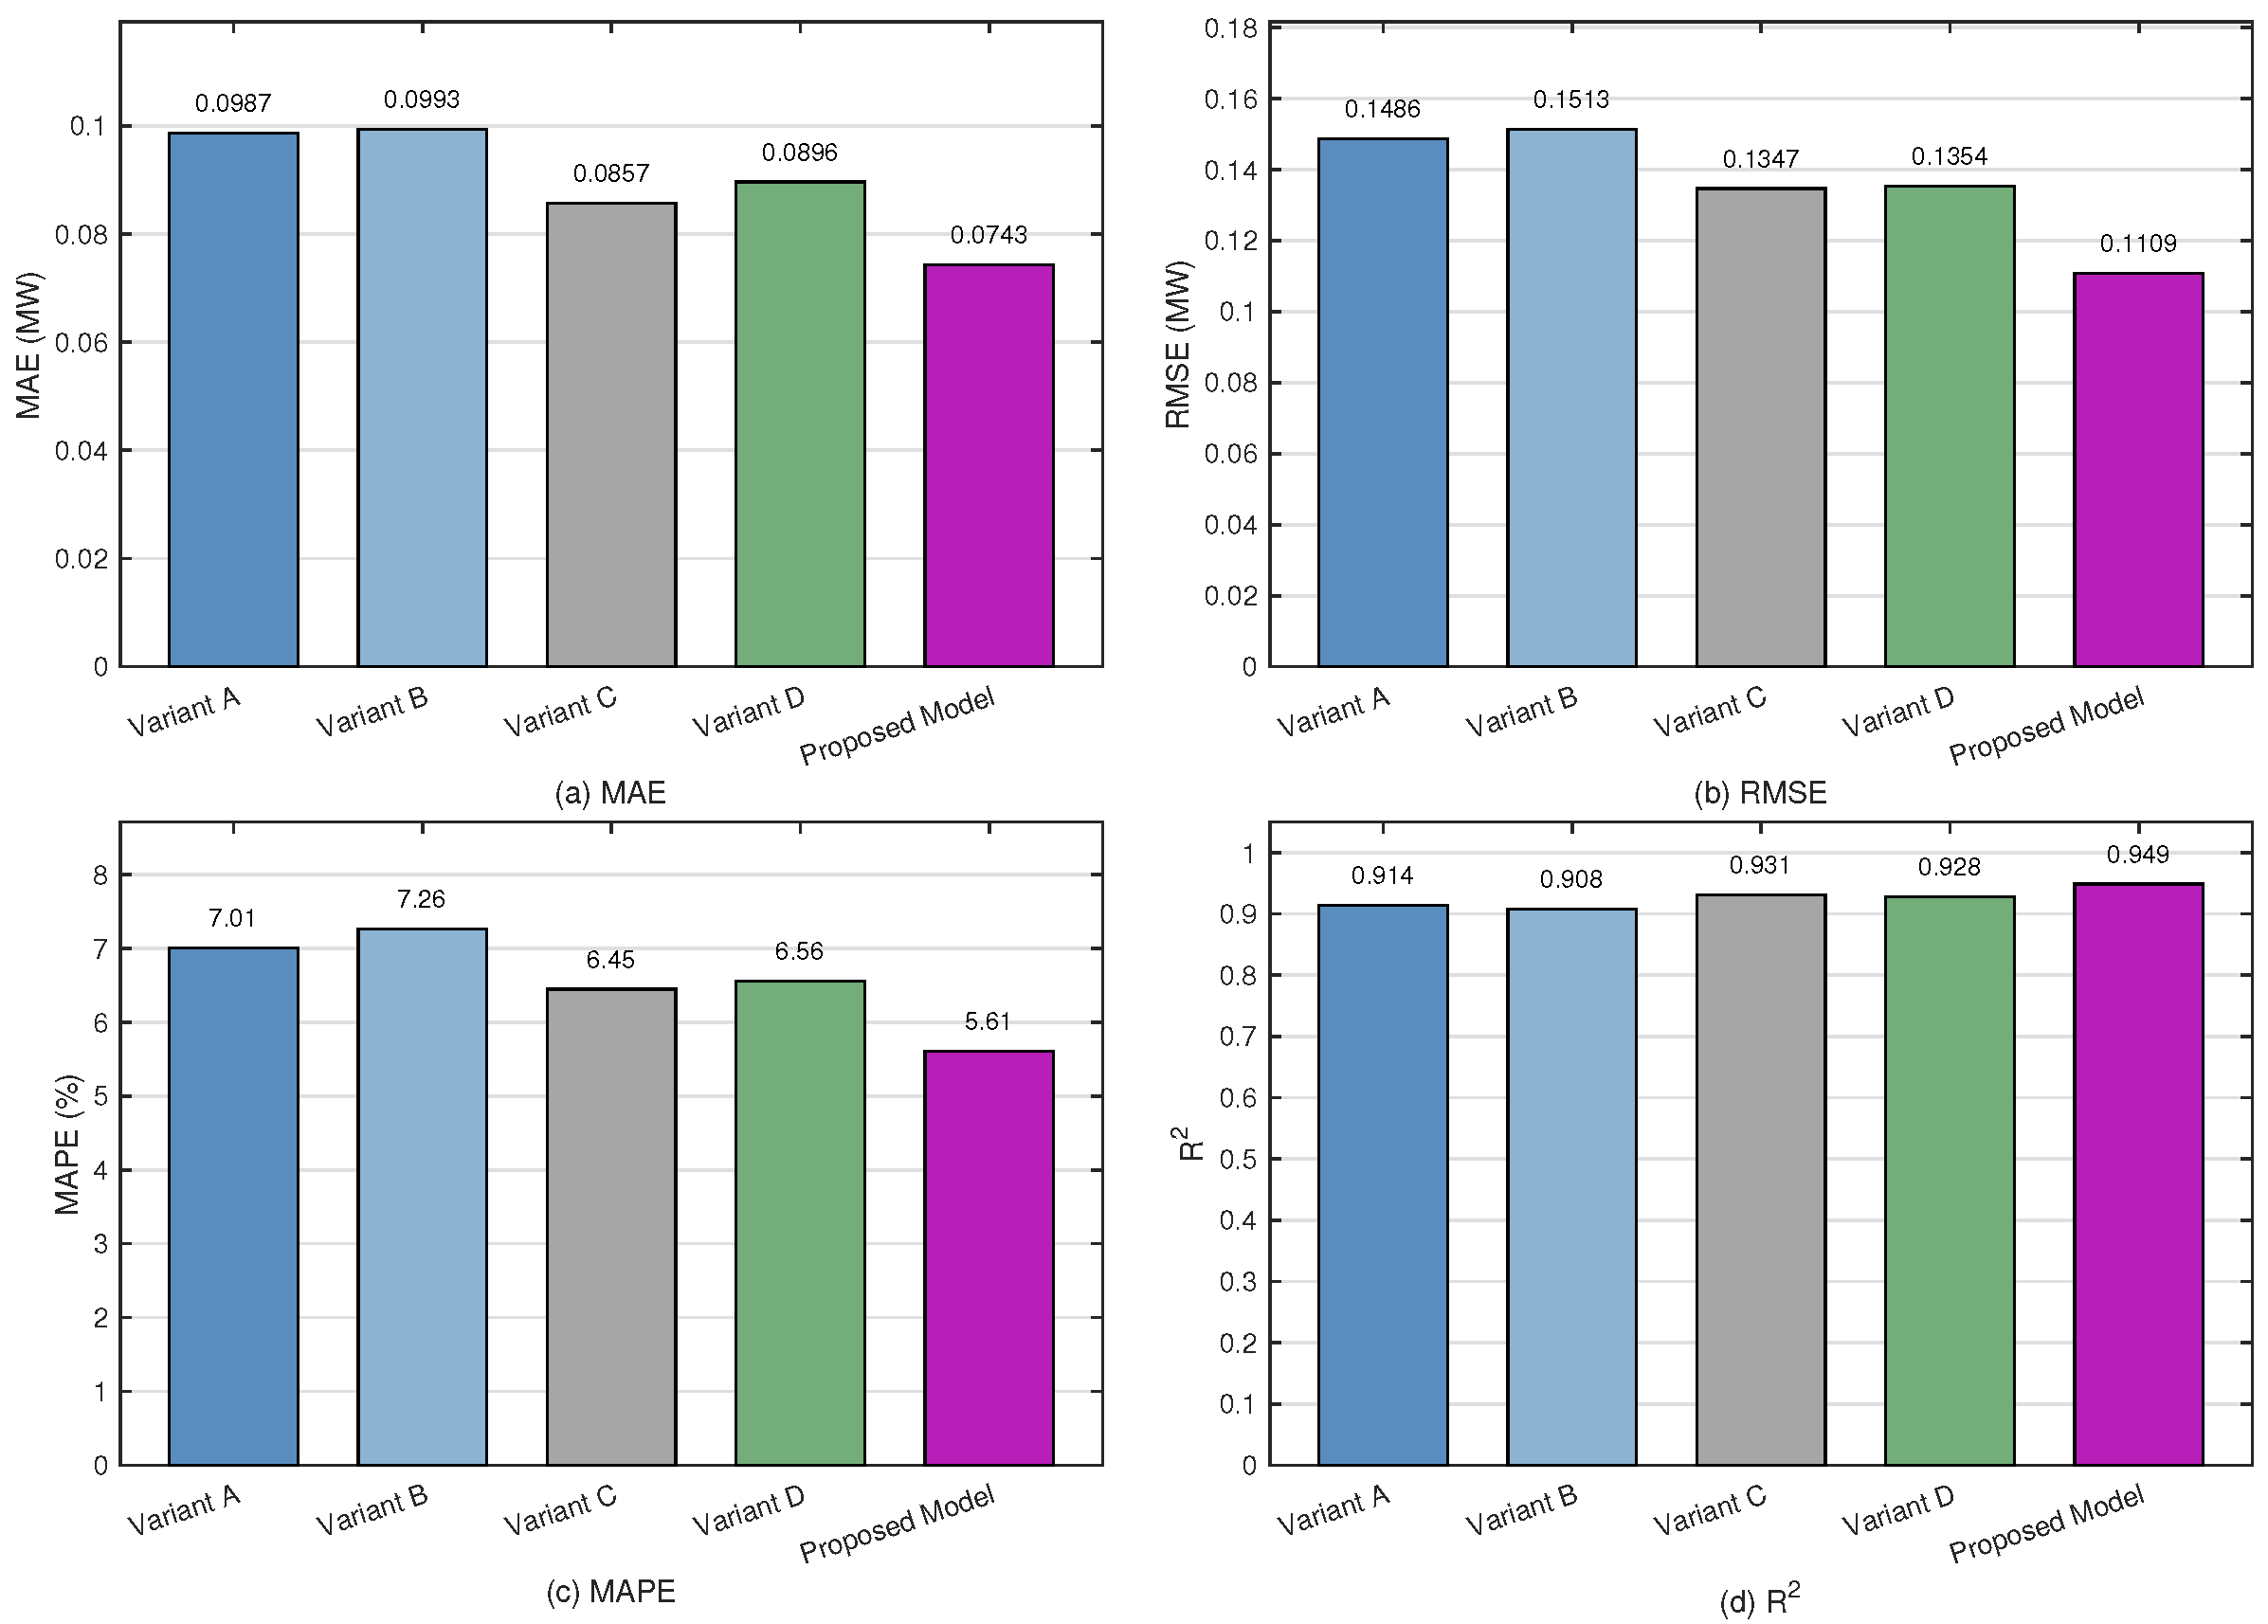
An ablation study is conducted to verify the effectiveness of the main components in TimeXer-Mamba. The complete model is used as the reference, and four variants are constructed by retaining only one branch, replacing the fusion strategy, or replacing the Mamba branch with a standard Transformer. All variants are trained and tested under the same settings. The results are listed in Table 6, and Figure 7 presents the corresponding graphical comparison using four separate subplots for MAE, RMSE, MAPE, and . Lower MAE, RMSE, and MAPE values indicate better performance, whereas a higher indicates better goodness of fit.
Table 6.
Comparison of ablation study results.
Figure 7.
Graphical comparison of MAE, RMSE, MAPE, and across the ablation variants and the proposed model.
The ablation results show that removing either branch increases the prediction error. Variant A, which retains only the Mamba module, obtains an MAE of 0.0987 MW and an RMSE of 0.1486 MW, while Variant B, which retains only the TimeXer module, gives an MAE of 0.0993 MW and an RMSE of 0.1513 MW. The two variants have similar error levels, and both are inferior to the complete model, indicating that exogenous-variable interaction and long-range temporal modeling provide complementary information.
Variant C replaces the gated fusion unit with additive fusion and obtains intermediate performance, with an MAE of 0.0857 MW and an RMSE of 0.1347 MW. This result indicates that the learnable gate provides a more suitable mechanism for combining the two branch representations than a fixed fusion form. Variant D, in which Mamba is replaced by a standard Transformer, also performs worse than the complete model. Under the present long-sequence setting, this comparison further demonstrates the advantage of the selective state-space branch in capturing long-range load evolution with lower computational overhead.
5.6. Computational Efficiency Analysis
Computational efficiency is evaluated on the same server equipped with an NVIDIA RTX 4090 graphics processing unit (GPU). The average per-step inference time of each main model is measured on the test set, and the results are reported in Table 7.
Table 7.
Comparison of prediction efficiency among different models.
Table 7 shows that TimeXer-Mamba requires 7.3 million parameters and 3.5 ms per inference step. Although LSTM has a shorter inference time, its RMSE is substantially higher. Compared with LSTM-Transformer, TimeXer-Mamba reduces the per-step inference time from 9.2 ms to 3.5 ms while also lowering the RMSE from 0.1223 MW to 0.1109 MW. Compared with the standard Transformer, the inference time is reduced from 15.3 ms to 3.5 ms, showing a significant efficiency advantage. This gain is consistent with the linear-complexity sequence modeling of the Mamba branch. Because ODE-MMF is performed as an offline preprocessing step, the additional decomposition cost does not directly increase the online per-step inference time.
The ODE-MMF preprocessing stage requires approximately 120 s. Since its parameters are derived from the statistical characteristics of historical data, they remain stable under normal operating conditions and can be reused unless substantial changes occur in the train timetable or line conditions. Therefore, the preprocessing parameters can be updated weekly or monthly rather than daily, and the one-time preprocessing cost has a negligible impact on the real-time performance of online inference.
Therefore, the proposed framework achieves a favorable balance between prediction accuracy and inference efficiency for second-level traction-load forecasting. The experimental results also indicate that the offline ODE-MMF preprocessing and the TimeXer-Mamba predictor are complementary, since the former improves the quality of the input subsequences and the latter strengthens the modeling of both exogenous-variable effects and long-range temporal evolution.
6. Conclusions
This paper addresses the challenges of high non-stationarity, complex spatiotemporal correlation, and long-range dependencies in electrified railway traction load sequences and proposes a short-term prediction framework integrating spatial correlation analysis, adaptive signal processing, and hybrid deep prediction. Based on experiments using second-level load data from a high-speed railway traction substation, the following conclusions are drawn for the evaluated operating conditions.
- (1)
- The proposed framework improves prediction accuracy under the evaluated conditions. The proposed ODE-MMF signal preprocessing method, by optimizing OD2 parameters via IWMA and adaptively fusing components using MTE, provides the prediction models with feature subsequences characterized by clear physical meaning and low information redundancy. The TimeXer-Mamba model collaboratively captures local fluctuations associated with exogenous variables and long-range temporal evolution. On the evaluated test set, the complete framework outperforms all evaluated baselines. Relative to the best-performing baseline, LSTM-Transformer, it achieves reductions of 9.61%, 9.32%, and 9.81% in MAE, RMSE, and MAPE, respectively, and its prediction curve exhibits closer agreement with the measured values.
- (2)
- The proposed framework provides a favorable balance between prediction accuracy and computational efficiency. Benefiting from the linear computational complexity of the Mamba module, the proposed model reduces the computational burden associated with Transformer-based long-sequence modeling. On the evaluated test set, it achieves lower prediction errors than the compared models and a shorter inference time than LSTM-Transformer. These results indicate its potential for real-time traction-load forecasting and related online decision-support applications.
Future work will evaluate the framework using data from additional traction substations, longer periods, and different operating conditions to further examine its generalizability. Further research will also investigate the integration of multi-source heterogeneous information, including train schedules, line topology, and meteorological data, together with physics-informed guidance to improve prediction accuracy and interpretability. In addition, the integration of the prediction model with scheduling decision-making systems and model lightweighting will be explored to support edge deployment.
Author Contributions
Conceptualization, H.C. and J.X.; methodology, H.C.; software, J.X.; validation, J.X., Q.G. and S.W.; formal analysis, J.X.; investigation, H.C.; resources, J.X.; data curation, H.C.; writing—original draft preparation, H.C.; writing—review and editing, J.X., Q.G. and S.W.; visualization, H.C.; supervision, J.X.; project administration, J.X. All authors have read and agreed to the published version of the manuscript.
Funding
This work was supported by the Academic and Technical Leader Training Program for Major Disciplines in Jiangxi Province (Grant No. 20232BCJ22004).
Data Availability Statement
The data that support the findings of this study are available from the corresponding author upon reasonable request.
Conflicts of Interest
Author Jinqing Xu was employed by the company POWERCHINA Jiangxi Electric Power Engineering Co., Ltd. The remaining authors declare that the research was conducted in the absence of any commercial or financial relationships that could be construed as a potential conflict of interest.
References
- Kano, N.; Tian, Z.; Chinomi, N.; Hillmansen, S. Comparison of Renewable Integration Schemes for AC Railway Power Supply System. IET Electr. Syst. Transp. 2022, 12, 209–222. [Google Scholar]
- Chen, Y.; Tian, H.; Zheng, G.; Liu, Y.; Grbić, M. Operation Strategy of Rail Transit Green Energy System Considering Uncertainty Risk of Photovoltaic Power Output. J. Mod. Power Syst. Clean Energy 2024, 12, 1859–1868. [Google Scholar] [CrossRef] [Scilit]
- Che, Y.; Wang, X.; Ge, L.; Lin, H.; Lyu, X.; Su, H.; Wang, H. A Review of Research on Traction Load Models and Modeling Methods for Electrified Railways. Renew. Sustain. Energy Rev. 2025, 219, 115869. [Google Scholar] [CrossRef] [Scilit]
- Tan, D.; Tang, Z.; Zhou, F.; Xie, Y. A Novel Hybrid Model Based on EMD-Improved TCN-Improved TST for Short-Term Railway Traction Load Forecasting. IEEE Trans. Transp. Electrif. 2025, 11, 6418–6427. [Google Scholar]
- Zhou, D.; Liu, Y.; Wang, X.; Wang, F.; Jia, Y. Combined Ultra-Short-Term Photovoltaic Power Prediction Based on CEEMDAN Decomposition and RIME Optimized AM-TCN-BiLSTM. Energy 2025, 318, 134847. [Google Scholar]
- Cao, L.; Shao, X.; Wang, C.; Gao, J. Residual-Corrected TSMixer with a RIME-Enhanced Decomposition Strategy for Photovoltaic Power Prediction. Electr. Power Syst. Res. 2026, 253, 112554. [Google Scholar] [CrossRef] [Scilit]
- Li, C.; Yao, M.; Lv, L.; Wu, Y.; Hao, Z. Optimization of VMD-LSTM Load Power Forecasting Model Based on OOLSSA Algorithm. J. Ind. Manag. Optim. 2025, 21, 2864–2884. [Google Scholar] [CrossRef] [Scilit]
- Ghimire, S.; Deo, R.C.; Casillas-Pérez, D.; Salcedo-Sanz, S. Electricity Demand Error Corrections with Attention Bi-Directional Neural Networks. Energy 2024, 291, 129938. [Google Scholar] [CrossRef] [Scilit]
- Shi, J.; Teh, J.; Alharbi, B. Improved Self-Attention Multi-Model Fusion for Load Forecasting in Regional Integrated Energy Systems. Eng. Appl. Artif. Intell. 2026, 166, 113557. [Google Scholar] [CrossRef] [Scilit]
- Udenze, P.I.; Gong, J.Q.; Soltani, S.; Li, D. A Deep Neural Network with Two-Step Decomposition Technique for Predicting Ultra-Short-Term Solar Power and Electrical Load. Appl. Energy 2025, 382, 125212. [Google Scholar] [CrossRef] [Scilit]
- Frei, M.G.; Osorio, I. Intrinsic Time-Scale Decomposition: Time–Frequency–Energy Analysis and Real-Time Filtering of Non-Stationary Signals. Proc. R. Soc. A Math. Phys. Eng. Sci. 2007, 463, 321–342. [Google Scholar]
- Li, H.; Tang, Y.; Liu, D. A Cross Informer Model Based on Dual-Layer Decomposition and Interpretability for Short-Term Electricity Load Forecasting. Alex. Eng. J. 2025, 129, 117–127. [Google Scholar] [CrossRef] [Scilit]
- Liu, H.; Pan, H.; Zheng, J.; Tong, J.; Zhu, M. Broad Distributed Game Learning for Intelligent Classification in Rolling Bearing Fault Diagnosis. Appl. Soft Comput. 2024, 167, 112470. [Google Scholar] [CrossRef] [Scilit]
- Je-Gal, H.; Lee, S.J.; Yoon, J.H.; Lee, H.S.; Yang, J.H.; Kim, S. A Novel Time-Frequency Feature Fusion Approach for Robust Fault Detection in a Marine Main Engine. J. Mar. Sci. Eng. 2023, 11, 1577. [Google Scholar] [CrossRef] [Scilit]
- Ma, C.; Zhang, C.; Yao, J.; Zhang, X.; Nazir, M.S.; Peng, T. Enhancement of Wind Speed Forecasting Using Optimized Decomposition Technique, Entropy-Based Reconstruction, and Evolutionary PatchTST. Energy Convers. Manag. 2025, 333, 119819. [Google Scholar] [CrossRef] [Scilit]
- Saeed, A.; Li, C.; Zhu, Q.; Ahmad, B. Deterministic Forecasts and Prediction Intervals for Wind Speed Using Enhanced Multi-Quantile Loss Based Dilated Causal Convolutions. IEEE Trans. Sustain. Energy 2025, 16, 2002–2014. [Google Scholar] [CrossRef] [Scilit]
- Rahman, R.; Moriano, P.; Khan, S.U.; Nguyen, D.C. Electrical Load Forecasting over Multihop Smart Metering Networks with Federated Learning. IEEE Internet Things J. 2025, 12, 38413–38426. [Google Scholar] [CrossRef] [Scilit]
- Cai, J.; Wang, Y.; Chen, Z.; Gao, Y.; Tang, G. A CNN-BiLSTM Short-Term Wind Power Forecasting Model Incorporating Adaptive Boosting. Meas. Sci. Technol. 2025, 36, 026210. [Google Scholar] [CrossRef] [Scilit]
- Zeng, S.; Liu, C.; Zhang, H.; Zhang, B.; Zhao, Y. Short-Term Load Forecasting in Power Systems Based on the Prophet-BO-XGBoost Model. Energies 2025, 18, 227. [Google Scholar] [CrossRef] [Scilit]
- Pentsos, V.; Tragoudas, S.; Wibbenmeyer, J.; Khdeer, N. A Hybrid LSTM-Transformer Model for Power Load Forecasting. IEEE Trans. Smart Grid 2025, 16, 2624–2634. [Google Scholar] [CrossRef] [Scilit]
- Fang, Q.; Liang, X.; Li, S.; Zhang, J.; Yang, X.; Guo, Z. A Novel Multi-Step Short-Term Power Forecasting Model for Electric Power Systems Based on Deep-Learning. IEEE Trans. Power Syst. 2025, 40, 4621–4633. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Y.; Zhang, T.; Tian, L. A TimeXer-Based Numerical Forecast Correction Model Optimized by an Exogenous-Variable Attention Mechanism. Comput. Mater. Contin. 2026, 86, 76. [Google Scholar] [CrossRef] [Scilit]
- Lu, K.; Gao, S.; Li, J.; Chen, K.; Yu, C. Prediction of Power System Ramping Demand Using Meteorological Features. IEEE Access 2025, 13, 85775–85788. [Google Scholar] [CrossRef] [Scilit]
- Gong, R.; Jiang, A.; Gong, R.; Wu, X.; Zhang, S. A Primary-Auxiliary Collaborative Power Load Forecasting Method Based on RBKA-PG-Mamba with Weather Feature-Enhanced Error Correction under Small Sample Datasets. Electr. Power Syst. Res. 2026, 253, 112558. [Google Scholar] [CrossRef] [Scilit]
- Li, P.; Zheng, X.; Xiang, S.; Hou, J.; Qin, Y.; Kurboniyon, M.S.; Ren, W. Channel Independence Bidirectional Gated Mamba with Interactive Recurrent Mechanism for Time Series Forecasting. IEEE Trans. Ind. Electron. 2025, 72, 14593–14602. [Google Scholar] [CrossRef] [Scilit]
- Liu, Z.; Jin, Y.; Zuo, M.J.; Feng, Z. Time-Frequency Representation Based on Robust Local Mean Decomposition for Multicomponent AM–FM Signal Analysis. Mech. Syst. Signal Process. 2017, 95, 468–487. [Google Scholar] [CrossRef] [Scilit]
- Ghasemi, M.; Deriche, M.; Trojovský, P.; Mansor, Z.; Zare, M.; Trojovská, E.; Abualigah, L.; Ezugwu, A.E.; Mohammadi, S.K. An Efficient Bio-Inspired Algorithm Based on Humpback Whale Migration for Constrained Engineering Optimization. Results Eng. 2025, 25, 104215. [Google Scholar] [CrossRef] [Scilit]
- Wang, Y.; Wu, H.; Dong, J.; Qin, G.; Zhang, H.; Liu, Y.; Qiu, Y.; Wang, J.; Long, M. TimeXer: Empowering Transformers for Time Series Forecasting with Exogenous Variables. In Proceedings of the Advances in Neural Information Processing Systems; Curran Associates, Inc.: Red Hook, NY, USA, 2024; Volume 37. [Google Scholar]
- Chen, T.; Li, L.; Fan, Y.; Liu, Y.; Xu, J. A Regional Short-Term Load Forecasting Model Based on a Cross-Attention Causal Spatio-Temporal Convolutional Network. Int. J. Electr. Power Energy Syst. 2025, 172, 111275. [Google Scholar] [CrossRef] [Scilit]
- Gu, A.; Dao, T. Mamba: Linear-Time Sequence Modeling with Selective State Spaces. In Proceedings of the First Conference on Language Modeling, Philadelphia, PA, USA, 7–9 October 2024. [Google Scholar]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.