


Highlights
What are the main findings?
- A dual-branch architecture (DBA) is proposed to decouple temporal modeling into parallel local convolutional and global attention streams.
- A task-aware gating mechanism is designed to adaptively fuse heterogeneous features based on acoustic confidence.
What are the implications of the main findings?
- The method resolves the conflict between the global smoothing of wav2vec 2.0 and the local discriminative needs of Connectionist Temporal Classification (CTC) alignment.
- The approach significantly improves robustness in fast-speech scenarios, achieving a 15.3% relative performance gain.
Abstract
Integrating wav2vec 2.0 with Connectionist Temporal Classification (CTC) for automatic speech recognition (ASR) often involves a trade-off between capturing global semantic consistency and maintaining local feature discriminability. This study proposes DBA-wav2vec 2.0, an architecture designed to manage these modeling requirements by decoupling temporal modeling into parallel local and global streams at the encoder–decoder interface. Depthwise separable convolutions are utilized to capture local acoustic structures, while a self-attention path is retained for long-range dependencies. A task-aware gating mechanism is introduced to integrate these heterogeneous features. By adjusting fusion weights based on acoustic input characteristics, the gate facilitates the refinement of posterior probability distributions, leading to more distinct alignment points. Experimental results on AISHELL-1 and ST-CMDS datasets show relative Character Error Rate (CER) reductions of 6.4% and 7.4%, respectively, compared to a baseline wav2vec 2.0 model. Further evaluations under varying speaking rates demonstrate a 15.3% relative improvement in fast-speech scenarios, suggesting that structural adaptation at the decoding interface can enhance the robustness of CTC-based systems against temporal variations.
1. Introduction
Automatic Speech Recognition (ASR) aims to convert continuous acoustic signals into text sequences. Deep learning has driven a paradigm shift in research toward End-to-End (E2E) architectures, which have become the core approach for current ASR systems [1], significantly simplifying topologies while enhancing recognition accuracy [2]. Early hybrid architectures, such as the cascading of Hidden Markov Models (HMMs) and Gaussian Mixture Models (GMMs) [3], relied heavily on manual feature engineering and suffered from lengthy modeling due to segmented optimization. The subsequent introduction of Bi-directional Long Short-Term Memory (Bi-LSTM) networks improved acoustic representation [4] but remained prone to error accumulation. With the maturation of E2E technologies, methods like joint modeling have further strengthened the ability to handle complex tasks [5]. Among these, the Connectionist Temporal Classification (CTC) algorithm has become a cornerstone of sequence modeling due to its ability to function without explicit alignment annotations [6]. Subsequently, Deep Speech 2 [7], attention mechanisms [8], and the Listen, Attend, and Spell (LAS) framework [9] further expanded the boundaries of modeling long-sequence dependencies.
1.1. State of the Research Field
Recently, Self-Supervised Learning (SSL) has positioned models like wav2vec [10] and wav2vec 2.0 [11]—which enhance feature discrimination through masked contrastive learning—as core technologies in contemporary ASR. E2E ASR significantly simplifies system structure and training workflows compared to traditional Deep Neural Network-Hidden Markov Model (DNN-HMM) [12]. Subsequent studies, such as HuBERT [13], have further enhanced the semantic abstraction depth of features. Such models excel in capturing long-range context and maintaining semantic consistency, demonstrating strong generalization potential in multilingual scenarios like Cross-lingual Speech Representation (XLS-R) [14].
To balance short-term local structures and long-range semantic dependencies, the academic community has explored parallel or branched temporal modeling architectures. Approaches represented by Branchformer [15] and E-Branchformer [16] construct parallel branches within the encoder layer to extract local continuous features and global dependencies separately. Zipformer [17] improves representation efficacy through the reorganization of multi-scale resolutions. However, most existing methods focus on intra-layer feature fusion to build general efficient representations, rarely performing differentiated structural adaptation specifically for the decoding interface or alignment mechanisms.
1.2. Problem Statement and Contribution
Mechanistic analysis indicates that while the wav2vec 2.0 encoder focuses on utilizing global context to capture deep semantics, the attention smoothing effect of deep Transformers often leads to rank degeneration in the temporal dimension, weakening feature discriminability [18]. In contrast, the convergence of CTC is highly dependent on the local discriminability of input features to form precise alignment “spikes,” and its optimization process frequently faces challenges related to path search uncertainty [19]. This inductive bias conflict—between global semantic bias and the need for local alignment precision—often induces temporal shifts in predicted peaks or boundary blurring [20]. Moreover, under CTC constraints, high-level representations tend to coarsen as the receptive field expands, making it difficult to preserve precise time-step boundary information [21]. Although architectures like Conformer [22] attempt to alleviate such conflicts, they are limited by unified modeling approaches, especially under drastic speaking rate fluctuations [23]. Similarly, while Branchformer employs parallel branches, it relies on intra-layer fusion designed for training encoders from scratch. When such blocks are stacked as adapters on top of pre-trained transformers, their continued mixing of attention mechanisms tends to exacerbate the “smoothing” issue without explicitly restoring local boundaries. In contrast, our approach introduces a “late-stage decoupling” inductive bias.
We argue that under the CTC paradigm, relying on a single temporal modeling path makes it difficult to balance alignment stability with semantic discriminability. To address this, this paper proposes a dual-branch architecture (DBA) for the wav2vec 2.0 framework, referred to as DBA-wav2vec 2.0. This architecture deploys parallel local perception and global attention channels at the top of the pre-trained encoder to construct a functionally decoupled modeling topology. We utilize depthwise separable convolutions (inspired by QuartzNet [24]) for the local branch to capture phoneme-level boundaries, fitting the conditional independence assumption of CTC. Furthermore, a task-aware dynamic gating strategy is designed to adaptively adjust the weight ratio of local details to global context. Experimental results on AISHELL-1 and ST-CMDS datasets demonstrate that this approach significantly enhances the sharpness of the posterior probability distribution and improves robustness in complex scenarios.
The remainder of this paper is organized as follows: Section 2 details the proposed DBA-wav2vec 2.0 architecture, including the design of the local and global branches and the task-aware branch fusion strategy. Section 3 describes the experimental setup and evaluates the performance on public Mandarin datasets. Section 4 provides a comprehensive discussion on alignment stability, the effectiveness of the dual-branch structure, and the impact of deployment strategies. Finally, Section 5 summarizes the conclusions of this study.
2. Methods
2.1. Overall Architecture
In E2E ASR tasks, the wav2vec 2.0 pre-trained encoder, with its multi-layer Transformer architecture, performs unified and deep contextual modeling on input speech. This design endows the model with a strong capability to capture semantic consistency across time steps, which is highly beneficial for downstream tasks centered on semantic discrimination. However, when this architecture is placed under the CTC framework, its inherent inductive bias reveals limitations: the training process of the CTC algorithm relies heavily on searching for monotonic alignment paths between sparse effective labels and numerous blank frames. This mechanism places extremely high demands on the local discriminability, boundary sensitivity, and alignment stability of features in the temporal dimension. In other words, while the Transformer tends to generate smooth global semantic representations, CTC decoding urgently requires precise local acoustic boundaries, creating a significant structural tension between their modeling objectives.
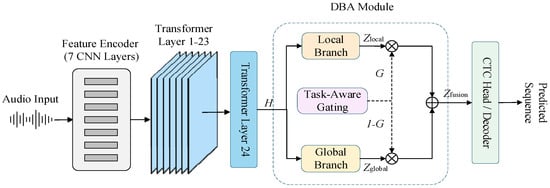
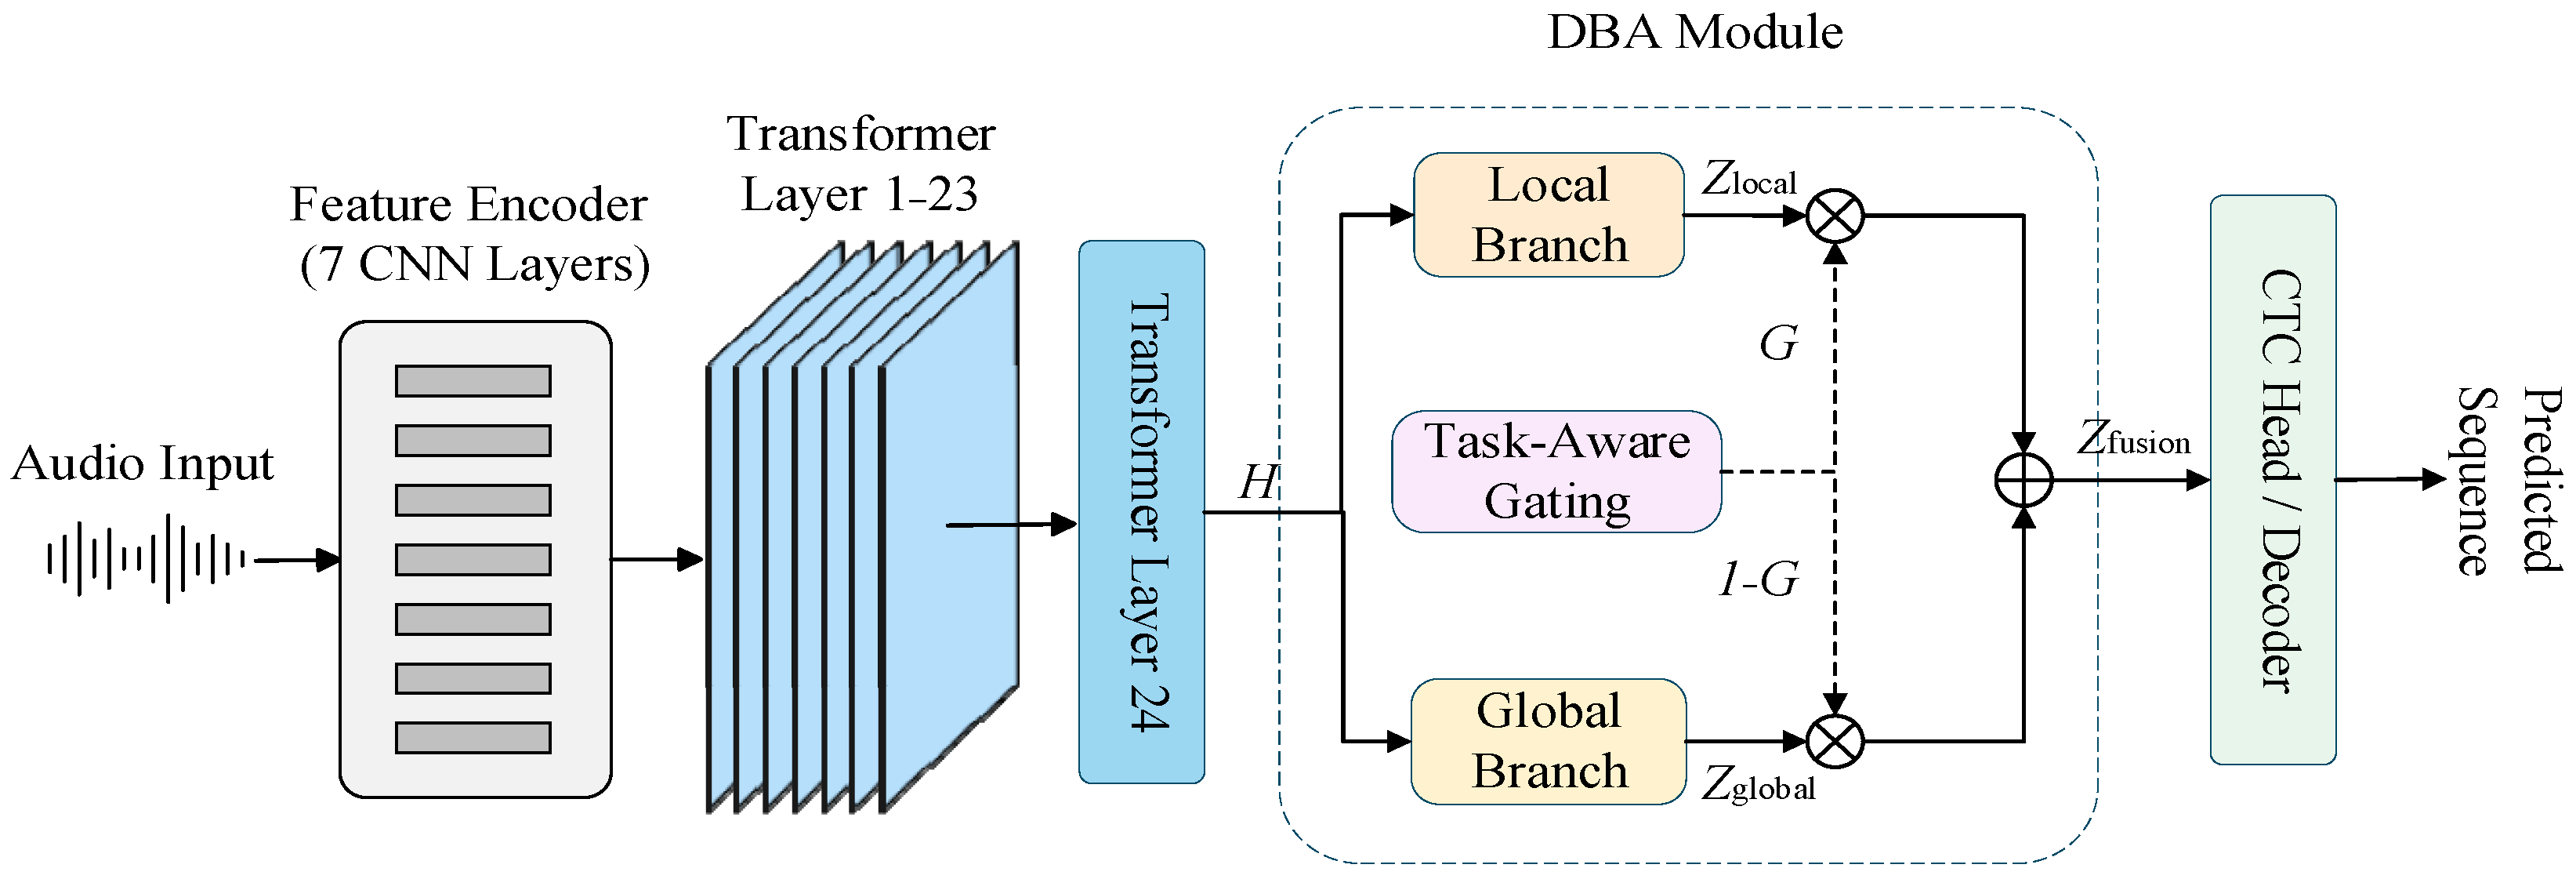
To resolve this conflict between modeling objectives, this paper abandons the traditional unified temporal modeling path and instead introduces an explicit DBA at the high level of the wav2vec 2.0 encoder (as shown in Figure 1). Unlike the single data stream of the original architecture, this design strategically deploys the core reconstruction module (DBA Module) after the top-level Transformer Layer 24. This topological change aims to implement a “divide-and-conquer” strategy: at the critical node before features are fed into the CTC decoding head, utilizing the decoupling characteristics of parallel paths preserves the rich semantic information learned by the deep network while specifically reinforcing local representation precision through a dedicated structure.
Figure 1.
Overall architecture of the proposed DBA-wav2vec 2.0 model. The audio input is processed by a 7-layer CNN Feature Encoder and 24 Transformer layers. The DBA Module performs dynamic feature fusion using a Local Branch and a Global Branch. Solid arrows represent the primary data flow, while dashed arrows indicate the distribution of gating coefficients and . Different colors are used to distinguish functional stages: feature encoding (grey and light blue), the DBA fusion module (orange and purple), and the CTC decoding stage (cyan).
Specifically, high-level features are diverted into two parallel paths with distinct functions: the Local Branch focuses on phoneme-level short-term continuous structures to enhance local separability between time steps, satisfying CTC’s need for alignment stability; the Global Branch continues to leverage the Transformer’s advantages, responsible for capturing long-range contextual dependencies to maintain semantic consistency. This design achieves an explicit separation of “alignment modeling” and “semantic modeling” tasks at the physical structural level within the CTC framework. To ensure the effective synergy of these two types of features, we further designed a Task-Aware Branch Fusion mechanism. This mechanism allows the model to adaptively adjust the weights of local and global information at different temporal positions according to the current alignment state and modeling needs. It is worth noting that since the dual-branch structure directly participates in the backpropagation of the CTC loss, the two paths are forced to learn differentiated temporal statistical properties during training. This division of labor cannot be equivalently achieved by simple module stacking or parameter weighting. Furthermore, probing studies on self-supervised models indicate that the top layers of encoders often tend to lose low-level acoustic details; thus, introducing a parallel local branch at the top provides an irreplaceable theoretical basis for compensating for acoustic alignment information.
In summary, the DBA-wav2vec 2.0 architecture proposes a temporal modeling reconstruction scheme oriented towards the CTC alignment mechanism. Unlike Conformer or Branchformer, which focus on fusing features within the encoder layers (intra-layer), this paper focuses on the systemic reconstruction at the decoding front-end, stripping and re-fusing functional roles in speech representation. The overall processing flow of the model is shown in Figure 1: the original audio is converted into low-level acoustic features via the Feature Encoder (composed of seven convolutional neural network (CNN) layers), then high-level representations are extracted through multi-layer Transformer encoding; on this basis, the dual-branch structure performs differentiated modeling of local and global features, which are finally sent to the CTC decoder after task-aware fusion. This approach fundamentally improves the model’s adaptability to CTC alignment stability while maintaining pre-trained semantic advantages.
2.2. Design of Local and Global Branches
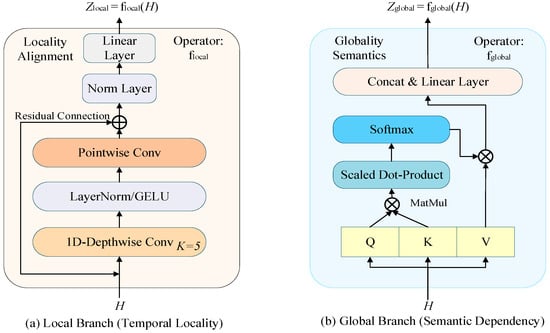
Speech signals naturally present multi-scale structural characteristics in the temporal dimension, which map to distinct modeling demands under the CTC architecture: short-term local context governs phoneme boundaries and time-step separability, serving as the cornerstone for stable alignment paths; whereas long-range context carries lexical and syntactic logic, directly determining the discriminative precision of the final recognition result. Based on this theoretical premise, we constructed an explicit dual-branch temporal modeling structure at the high level of the encoder to decouple and optimize these two mutually constraining objectives. The detailed design is shown in Figure 2.
Figure 2.
Detailed design of (a) the Local Branch and (b) the Global Branch. Functional modules are distinguished by colors: orange blocks represent convolutional layers, blue blocks denote attention-related operations, and yellow blocks represent Q, K, V matrices. Solid arrows indicate the data flow, while the curved arrow in (a) specifically represents the residual connection. Symbol denotes element-wise addition and denotes multiplication operations.
Let the high-level feature sequence output by the wav2vec 2.0 encoder be:
where denotes the sequence length (number of time steps) and represents the hidden dimension of the encoder features.
The Local Branch is used to characterize the local continuous structure in the temporal dimension, and its internal operator composition is shown in Figure 2a. We employ multi-layer 1D Depthwise Separable Convolutions to construct the local branch operator . This convolution paradigm decouples spatial modeling from channel mapping and can capture strong temporal translation invariance features with an extremely low parameter load [25]. This design philosophy was first proven efficient in visual tasks [26]. Meanwhile, reasonable feature extraction and pooling operations are crucial for maintaining local discriminability when processing the temporal representation of acoustic features [27]. This operator reinforces boundary sensitivity and temporal separability between adjacent time steps through a fixed-size local receptive field (). To ensure the effective flow of low-level acoustic details, this branch uses a Residual Connection (as shown on the left of the figure) for identity path mapping and utilizes a linear mapping layer to process the feature dimension to remain consistent with the encoder dimension . Through this convolutional structural constraint, the model is forced to introduce spatial locality bias within the time step, making its modeling objective serve the local separability requirements during the time alignment process. Unlike generic blocks (e.g., Conformer) that sandwich convolutions between attention layers, our parallel design ensures that the local acoustic cues are not diluted by global mixing before reaching the fusion gate. This lightweight convolutional constraint has been proven to have higher inductive bias efficiency than the self-attention mechanism in capturing local phoneme-level acoustic patterns. Its output is represented as:
The modeling goal of this branch is not semantic abstraction but rather serving the local separability requirements of the alignment process.
The Global Branch is used to model long-range dependencies across time steps. Its output is represented as:
where denotes the global modeling function based on Multi-Head Self-Attention (MHSA), which is used to capture long-range contextual information and semantic consistency in the speech sequence [28]. This branch continues the semantic modeling inductive bias formed during the wav2vec 2.0 pre-training phase and is an important source of final recognition discriminability. As shown in Figure 2b, this branch captures long-range consistency through QKV mapping and Scaled Dot-Product Attention operators. By comparing subgraphs Figure 2a,b, it is evident that the two paths have significant mathematical complementarity, providing “micro-precision” and “macro-background” for the subsequent alignment task, respectively.
It must be emphasized that the proposed dual-branch architecture is not a simple stacking of parallel computations but rather achieves deep decoupling of “alignment stability modeling” and “semantic discriminability modeling” at the structural level. Unlike existing strategies of layer-by-layer fusion inside the encoder, we specifically deploy the branching module after the top-level output of the encoder. This strategic layout, under the constraint of the CTC loss function, forces different branches to learn differentiated temporal statistical characteristics, thereby establishing specific functional divisions for each branch in the physical structure.
2.3. Task-Aware Branch Fusion Strategy
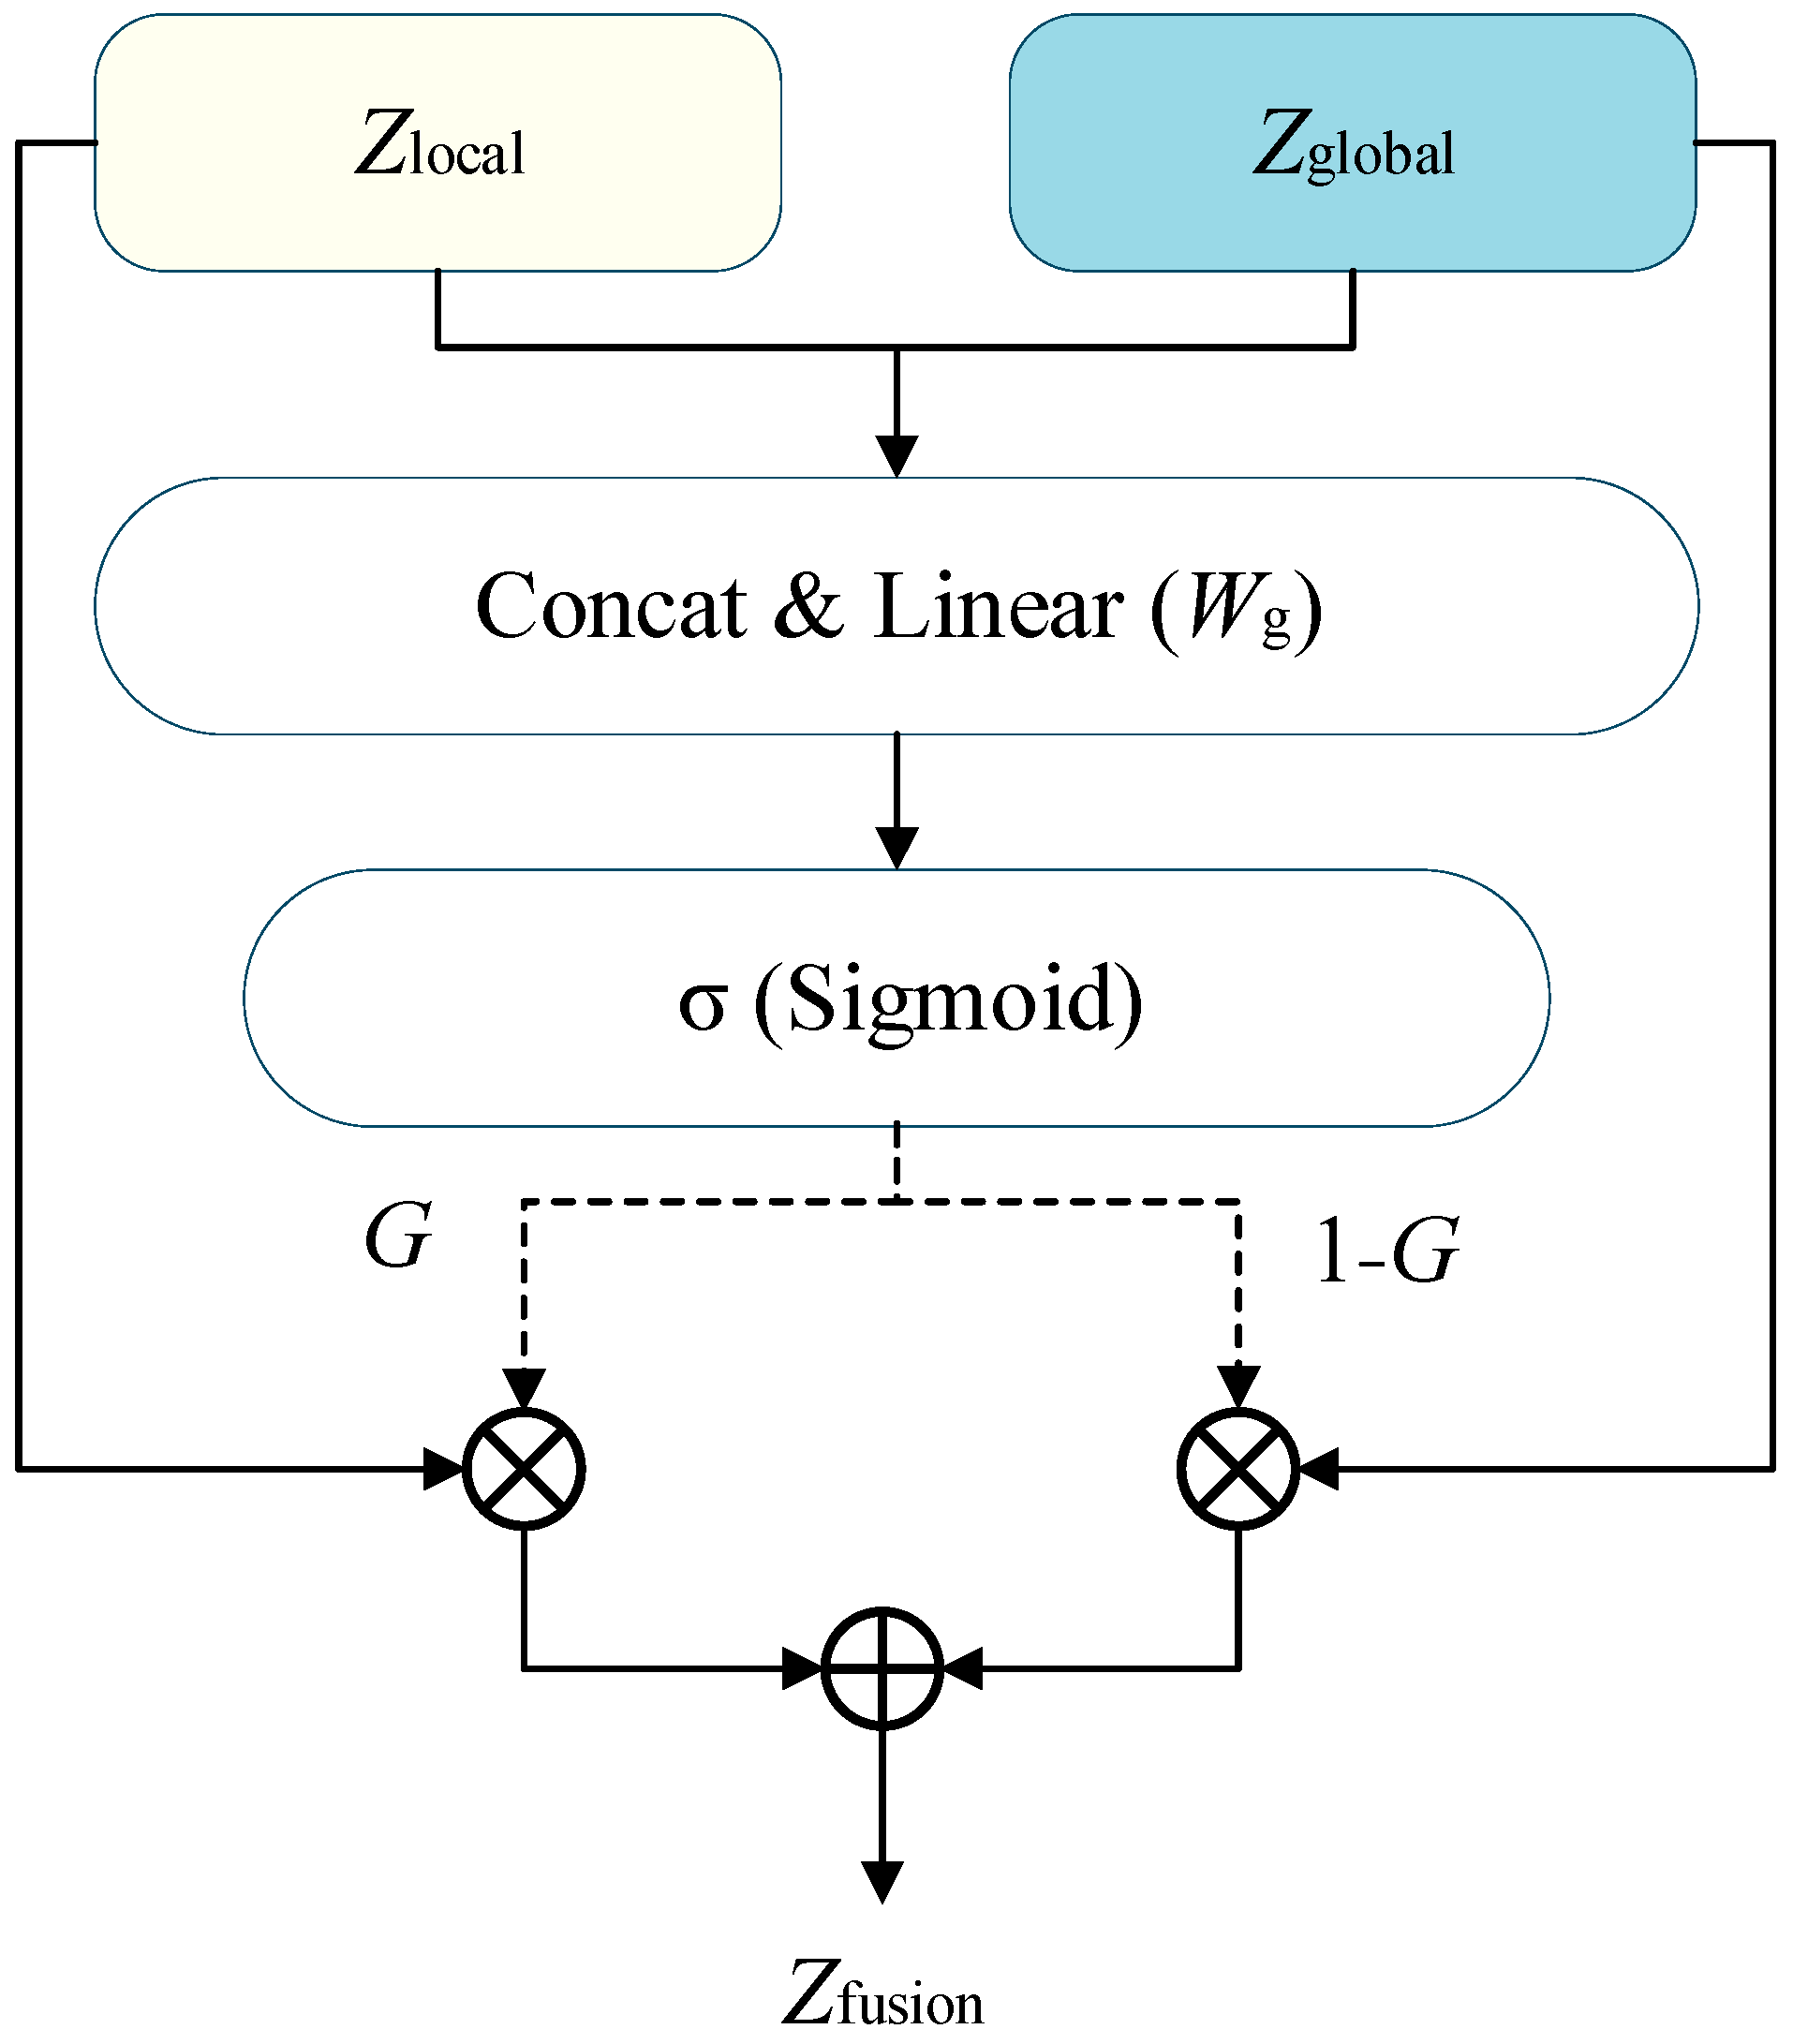
Under the CTC framework, the supervision signal in the temporal dimension exhibits high sparsity, leading to significant heterogeneity in the modeling demands of different time steps in the alignment path: critical time steps corresponding to effective labels or boundaries have strict requirements for local separability and alignment stability; while the vast majority of blank time steps rely more on contextual semantic consistency to maintain overall discriminability. Addressing this characteristic, we propose a Task-Aware Branch Fusion strategy, aiming to allow the model to adaptively balance the contribution weights of local and global branches on the time axis. The logic interaction and calculation flow of this mechanism are shown in Figure 3, where solid arrows depict the data path of feature tensors, and dashed arrows represent the generation and flow of gating control signals.
Figure 3.
Diagram of the Task-Aware Gating Mechanism. The light yellow and light blue boxes represent the input features from the local and global branches, respectively. Solid arrows denote the primary flow of feature representations, while dashed arrows indicate the distribution of the calculated gating weights ( and ). The symbols and represent element-wise multiplication and addition, respectively.
Research by Liu et al. [29] shows that effective fusion of multi-level acoustic features can significantly improve the representation capability of deep learning models for speech signals. Inspired by this, we employ a learnable gating mechanism to fuse the two branches. This design references the processing method of Gated Units in multi-source information fusion [30], formulated as:
where represents the Sigmoid activation function, denotes feature concatenation, and are learnable gating parameter matrices, is the dimension-wise gating weight matrix, and denotes element-wise multiplication. This dynamic selection mechanism draws on the adaptive adjustment concept of Gated Linear Units (GLU) in long-sequence dependency modeling [31]. From the topological connection in Figure 3, it can be observed that the concatenated features are first input into the gate generation unit to learn the dimension-level weight . Subsequently, a polarity shift occurs in the signal flow: the left path weight remains , while the right path generates a complementary weight factor via a subtraction operator. These two complementary signals act on the outputs of the original local branch and global branch, respectively. This dynamic game mechanism not only ensures that contains two types of complementary features but also allows the weight to be fine-tuned in real-time as the input task changes. It is important to note that this “task-aware” capability is implicitly learned through the backpropagation of the CTC objective: the model spontaneously develops a mapping where prioritizes the local branch during transient label prediction to capture precise boundaries, while shifting towards the global branch during blank-dominated segments. By optimizing this mapping end-to-end, the gate functions as a discriminative filter that effectively bridges the gap between pre-trained semantic representation and CTC alignment needs, without requiring explicit external task state inputs. This provides the model with high resource configuration flexibility at critical positions for CTC decoding (i.e., time points predicting non-Blank labels).
The core of this fusion mechanism lies in that the learning process of its gating weights is directly controlled by the constraints of the CTC loss function. This enables the gating mechanism to perform discriminative adjustments at the feature dimension level, automatically identifying which feature components need reinforced local alignment and which should focus on semantic representation. During training, gating parameters spontaneously adjust the dependence on local or global branches based on the specific function of each time step in the alignment path, thereby achieving a dynamic balance between alignment modeling and semantic modeling at the physical structural level. Unlike traditional fixed weighting or naive feature concatenation, this task-aware fusion mechanism forces the dual-branch structure to form a clear functional division under the CTC framework, which is key to the significant improvement in alignment stability and recognition performance achieved by this method.
2.4. Module Training and Optimization
The overall model uses CTC loss as the training objective, defined as:
where is the target text sequence, and is the fused encoder output. During training, the local branch, global branch, and task-aware gating parameters jointly participate in end-to-end optimization.
Benefiting from the dual-branch structure being placed directly in the backpropagation loop of CTC alignment constraints, the two paths gradually evolve distinct temporal statistical representations during training iterations. The unique “Peaky Distribution” characteristic of the CTC algorithm actually plays an implicit guiding role: it drives the gating weights in Figure 3 to produce a significant polarity shift towards the local branch (Figure 2a), which is responsible for capturing short-term structures, at the transients where label prediction occurs, thereby precisely locking temporal boundaries. It must be pointed out that this functional differentiation does not rely on additional external supervision signals but originates from the deep coupling and synergistic induction between the physical structure design and the CTC training mechanism. In summary, while maintaining the standard CTC decoding framework unchanged, the proposed method successfully implements a structural reconstruction of the wav2vec 2.0 high-level temporal modeling paradigm, providing a feasible optimization path oriented towards the CTC alignment mechanism for end-to-end speech recognition models.
3. Results
3.1. Experimental Setup
The experiments were conducted on two representative public Mandarin speech recognition datasets. The first is AISHELL-1 [32], which contains approximately 178 h of Mandarin recordings from 400 speakers. Due to its standardized content and high annotation consistency, it is widely regarded as a benchmark for evaluating the basic acoustic modeling capabilities of E2E systems. The second is the ST-CMDS dataset [33], containing approximately 100,000 short speech sequences. Its key feature is the inclusion of diverse speaking styles from natural interaction scenarios, characterized by drastic speaking rate fluctuations and numerous acoustic variants, which effectively validates the model’s alignment robustness and generalization in complex acoustic conditions. In the experiments, all audio data were resampled to 16 kHz, and Global Variance Normalization (GVN) was applied to eliminate the interference of recording equipment gain differences.
For acoustic feature extraction and modeling, this study utilized the pre-trained model jonatasgrosman/wav2vec 2.0-large-xlsr-53-chinese-zh-cn for initial weights. This model, based on the wav2vec 2.0-Large architecture, was pre-trained on a massive multi-source Chinese corpus and possesses strong multi-scale feature representation capabilities. The baseline system employs the standard wav2vec 2.0 encoder followed by a CTC decoding layer. The proposed DBA-wav2vec 2.0 model implements structural reconstruction at the high level of the encoder: the local branch is constructed via multi-layer 1D depthwise separable convolutions (Conv1D) with a kernel size of 5 to capture fine-grained spectral evolution and transient boundary features; the global branch retains the self-attention mechanism to assist in semantic error correction. These two branches are integrated through a Task-Aware Gating mechanism, which adaptively adjusts the feature weights based on the confidence of the acoustic input. To ensure fairness and rigor, both the baseline and DBA-wav2vec 2.0 used identical experimental configurations for fine-tuning.
Regarding the training strategy, a two-stage end-to-end fine-tuning method was adopted using the AdamW optimizer [34] with an initial learning rate of . To ensure stability and prevent local optima, a Tri-stage Scheduler was employed, including a 10% linear warm-up, 40% constant high learning rate training, and 50% linear annealing. The experimental environment was based on NVIDIA A100 GPUs and the PyTorch framework (version 2.1.0) [35]. The primary evaluation metric is the Character Error Rate (CER). To ensure a fair and reproducible comparison, the Transformer-CTC and Conformer-CTC baselines were configured with a 12-layer encoder structure, a hidden dimension of 512, 8 attention heads, and a feed-forward dimension of 2048. The Conformer-CTC additionally employs depthwise separable convolutions with a kernel size of 15. All models were strictly aligned in terms of experimental conditions: no data augmentation (such as speed perturbation) or auxiliary loss functions were used during fine-tuning, and only Greedy Search was applied during the CTC decoding phase. This “minimalist” comparison aims to purely verify the efficiency of the temporal modeling structure on feature extraction. In the experimental reproduction and benchmark settings, we strictly followed the general evaluation criteria of open-source toolkits such as WeNet (version 3.0.0) [36].
3.2. Performance and Alignment Analysis
Table 1 shows the performance comparison across different architectures. Although the baseline wav2vec 2.0 already exhibits high performance, the proposed DBA-wav2vec 2.0 achieves relative CER reductions of 6.4% on AISHELL-1 and 7.4% on ST-CMDS with a minimal parameter increase of 4.1%.
Table 1.
Comparison of performance and parameters across different architectures.
To ensure that the observed performance gains are robust and not artifacts of random initialization variance during the fine-tuning of large-scale pre-trained models, we further evaluated the baseline and the proposed DBA-wav2vec 2.0 on the AISHELL-1 dataset across four different random seeds (including the one reported in Table 1). The baseline yielded an average CER of 6.58% (±0.05), whereas the proposed DBA-wav2vec 2.0 achieved a stable average CER of 6.17% (±0.03). The consistent absolute improvement significantly exceeds the standard deviation margin. Even the highest CER variation in the proposed model outperforms the lowest CER variation in the baseline, confirming that the architectural correction introduced by the dual-branch design robustly enhances acoustic-to-text alignment precision regardless of initialization variance.
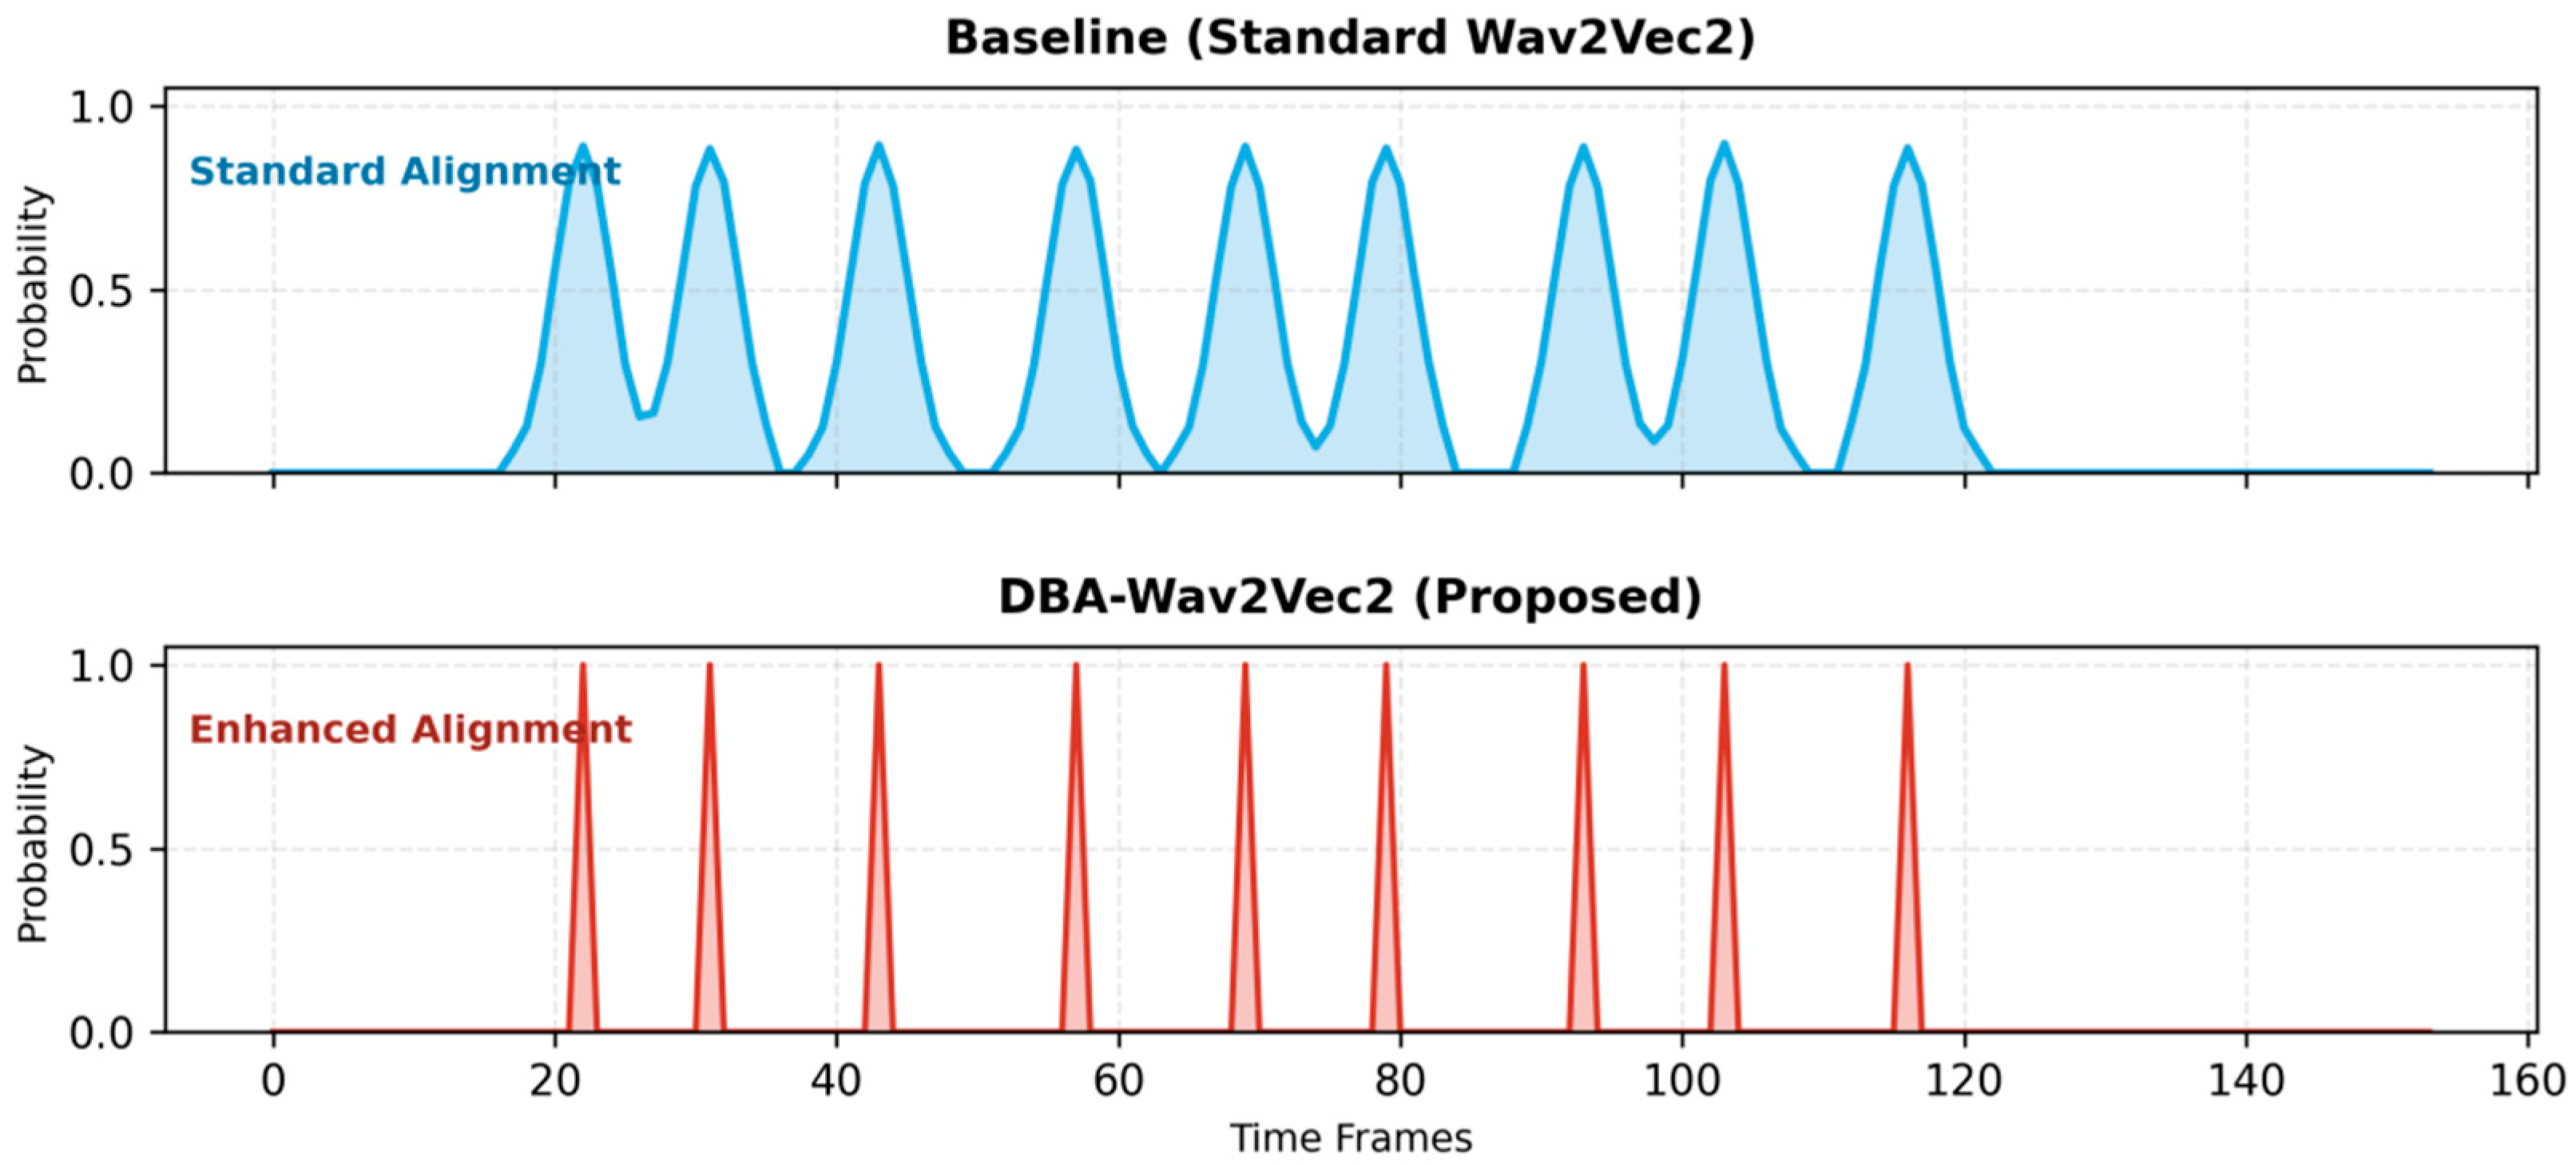
To investigate the microscopic impact of the DBA structure on CTC alignment, we visualized the posterior probability distributions in Figure 4. The baseline displays “Broad Peaks” with high temporal uncertainty. In contrast, DBA-wav2vec 2.0 generates “Sharp Spikes” with highly focused energy, indicating that the local branch successfully corrects the global smoothing effect of the Transformer and enhances the precision of phoneme boundary detection.
Figure 4.
CTC probability distribution comparison between the Baseline and DBA-wav2vec 2.0.
3.3. Robustness Under Varying Speaking Rates
We further evaluated the robustness of the model on the ST-CMDS test set categorized by speaking rate (characters per second). The results are summarized in Table 2.
Table 2.
CER performance comparison under different speaking rates on the ST-CMDS dataset.
As shown in Table 2, the baseline performance degrades significantly in the “Fast” speech category (CER increasing to 10.45%) due to compressed phoneme durations. However, DBA-wav2vec 2.0 achieves a 15.3% relative improvement in this category, proving that the convolutional local branch effectively locks onto high-dynamic acoustic signals where standard self-attention fails.
4. Discussion
To isolate the key factors driving performance improvements and to evaluate the robustness of the proposed DBA-wav2vec 2.0, this discussion is structured into a hierarchical validation framework. We first provide a microscopic analysis of the model’s alignment stability to characterize the impact of our dual-branch design (Section 4.1). We then disentangle the architectural contributions by verifying the necessity of each component and fusion strategy (Section 4.2). Subsequently, we compare our method against generic adapter architectures to evaluate its generalization potential (Section 4.3). Finally, we perform a systematic exploration of the local modeling design space—including operator configuration and deployment strategy (Section 4.4)—to identify the optimal architectural configuration.
4.1. Analysis of Alignment Stability via Posterior Distributions
The performance gains can be interpreted through the lens of alignment stability. To objectively substantiate this claim, we extracted the posterior probability distributions across the test set to compute two quantitative metrics: Average Alignment Entropy and Average Peak Width. The statistical results are presented in Table 3.
Table 3.
Quantitative evaluation of CTC alignment stability on the AISHELL-1 test set.
As shown in Table 3, the baseline model exhibits a high average alignment entropy of 0.582 and an average peak width of 3.64 frames. This corresponds to the observation that the baseline model exhibits “Broad Peaks” in its posterior probability distribution, as visualized in Figure 4, indicating temporal uncertainty and blurred phoneme boundaries.
In contrast, the proposed architecture significantly reduces the alignment entropy to 0.247 and narrows the average peak width to 1.28 frames. Consistent with these metrics, DBA-wav2vec 2.0 generates “Sharp Spikes” with highly focused energy. This quantitative validation confirms that the local branch successfully compensates for the “attention smoothing effect” inherent in deep Transformer layers. By sharpening the peaks, the model reduces path search uncertainty in CTC, leading to more precise and stable acoustic-to-text alignment.
4.2. Effectiveness of the Dual-Branch Architecture
Ablation studies in Table 4 verify our working hypothesis that decoupling local and global streams is superior to unified modeling. To explicitly analyze the architectural contributions, we evaluated three variants: “Global-only” retains the self-attention path but removes the local convolutional branch; “Local-only” utilizes depthwise separable convolutions while excluding the global attention mechanism; and “Parallel Dual-branch” combines both streams via static summation rather than the proposed gating strategy.
Table 4.
Ablation study of DBA components and fusion strategies.
The results indicate that the Task-Aware Gating mechanism allows for a “dynamic division of labor” that adapts to non-stationary acoustic signals more effectively than static addition.
Furthermore, we assessed the practical real-world applicability of the DBA-wav2vec 2.0 regarding computational overhead. Measured on a single A100 GPU with a batch size of 1 for 10-s audio segments, the DBA module introduces a marginal increase in computational cost as detailed in Table 5.
Table 5.
Computational complexity and inference latency analysis.
As shown in Table 5, the local convolutional branch introduces a marginal increase in computational overhead. Specifically, the FLOPs increase by approximately 6.9%, and the average inference latency increases by 3.4 ms. Given the significant CER reduction of 6.4% on the AISHELL-1 dataset, we consider this computational cost to be well-justified. The depthwise separable convolutions are highly efficient and effectively leverage modern GPU parallelization, ensuring that the architecture remains suitable for practical, real-time ASR systems.
4.3. Comparison with Generic Adapter Architectures
Beyond the internal component analysis, we further verified whether the performance gains stem from our specific architectural design or merely from increasing model parameters. We compared the proposed DBA against standard Conformer and Branchformer blocks acting as adapter heads on top of the same frozen wav2vec 2.0 backbone. To ensure a fair comparison, these blocks were configured to maintain a strictly comparable parameter budget (approximately 13.1 M added parameters) to our method.
As shown in Table 6, while the generic Conformer and Branchformer blocks provide modest performance gains (CER 6.44% and 6.38%, respectively), they are outperformed by the proposed DBA (6.15%). This confirms that simply stacking generic blocks continues to rely heavily on self-attention mechanisms, which may not effectively counteract the semantic smoothing of the pre-trained encoder. In contrast, the DBA’s explicit decoupling and task-aware gating offer a more suitable inductive bias for correcting alignment boundaries in CTC-based fine-tuning.
Table 6.
Performance comparison of different adapter architectures with comparable parameter budgets on AISHELL-1.
4.4. Interpretation of Operator Choice and Deployment Strategy
The sensitivity to kernel size (Table 7) and deployment depth (Table 8) provides insights into the structural requirements of CTC systems.
Table 7.
Ablation of local branch operators.
Table 8.
Impact of DBA module deployment location.
The optimal performance at Layer 24 confirms that the “semantic smoothing” accumulated through deep Transformer layers is the primary bottleneck for CTC alignment. Introducing the local branch at the top serves as a “re-alignment” mechanism that restores fine-grained acoustic boundaries before decoding.
5. Conclusions
In this paper, we addressed the core conflict between the “semantic smoothing effect” inherent in wav2vec 2.0 high-level representations and the “local discriminability” required by CTC decoding. We proposed DBA-wav2vec 2.0, a dual-branch attention speech recognition architecture specifically oriented toward the CTC alignment mechanism. Unlike traditional methods that focus on parameter tuning within a single path, this study reconstructed the temporal modeling logic of speech representation at the physical structural level. By explicitly constructing decoupled local and global parallel branches at the top of the encoder and introducing a dimension-wise task-aware gating mechanism, we achieved an adaptive fusion of feature flows optimized for CTC characteristics.
Empirical research on the AISHELL-1 and ST-CMDS datasets demonstrates that DBA-wav2vec 2.0 achieves relative CER reductions of 6.4% and 7.4%, respectively, while maintaining a nearly constant parameter scale. Notably, the model achieved a significant 15.3% performance leap in fast-speech scenarios. This work demonstrates that targeted structural correction at the encoder–decoder interface is a highly effective strategy for optimizing self-supervised representations for downstream ASR tasks. Future research will explore the integration of this architecture with other self-supervised frameworks and its performance in multi-speaker environments. Furthermore, while our dual-branch architecture is theoretically agnostic to the speech representation backbone, its synergy with other architectures (e.g., HuBERT or WavLM) and its generalization across different languages and decoding frameworks (e.g., RNNT or attention-based decoders) require further empirical verification. These aspects, alongside a detailed latency analysis for real-time streaming, represent the prioritized agenda for our future work, as the current study is primarily optimized for the CTC-based alignment bottleneck.
Author Contributions
Conceptualization & methodology, H.H. and C.T.; validation, C.T.; formal analysis, P.T. and C.T.; investigation, H.H. and C.T.; data curation, C.T.; writing—original draft preparation, H.H. and C.T.; writing—review and editing, H.H., P.T. and C.T.; visualization, P.T. and C.T.; supervision, P.T. and H.X.; project administration, H.H. and P.T.; funding acquisition, P.T. and H.X. All authors have read and agreed to the published version of the manuscript.
Funding
This work was supported by the Postgraduate Research and Practice Innovation Program of Jiangsu Province [Grant No.: KYCX23_1083].
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The datasets analyzed in this study are publicly available. The AISHELL-1 dataset can be found at http://www.openslr.org/33/ (accessed on 1 May 2025). The ST-CMDS dataset can be found at http://www.openslr.org/38/ (accessed on 1 May 2025).
Acknowledgments
During the preparation of this manuscript, the authors used ChatGPT (OpenAI, GPT-4, accessed on 5 February 2026) for text editing and English language polishing. The authors have reviewed and edited the output and take full responsibility for the content of this publication.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| ASR | Automatic Speech Recognition |
| CTC | Connectionist Temporal Classification |
| CER | Character Error Rate |
| DBA | Dual-Branch Architecture |
| SSL | Self-Supervised Learning |
References
- Chen, J.; Bai, B.; Wang, D.; Yan, D.Q.; Wang, R.D. Review of adversarial example attacks and defenses for automatic speech recognition systems. J. Chin. Comput. Syst. 2022, 43, 466–474. [Google Scholar]
- Li, J. Recent advances in end-to-end automatic speech recognition. arXiv 2021, arXiv:2111.01690. [Google Scholar] [CrossRef] [Scilit]
- Hinton, G.; Deng, L.; Yu, D.; Dahl, G.E.; Mohamed, A.-R.; Jaitly, N.; Senior, A.; Vanhoucke, V.; Nguyen, P.; Sainath, T.N.; et al. Deep neural networks for acoustic modeling in speech recognition: The shared views of four research groups. IEEE Signal Process. Mag. 2012, 29, 82–97. [Google Scholar] [CrossRef] [Scilit]
- Graves, A.; Schmidhuber, J. Framewise phoneme classification with bidirectional LSTM and other neural network architectures. Neural Netw. 2005, 18, 602–610. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Ou, J.; Zan, H.; Xu, H. End-to-end speech-to-text translation based on multimodal joint modeling. J. Chin. Comput. Syst. 2025, 46, 2338–2344. [Google Scholar]
- Graves, A.; Fernández, S.; Gomez, F.; Schmidhuber, J. Connectionist temporal classification: Labelling unsegmented sequence data with recurrent neural networks. In Proceedings of the 23rd International Conference on Machine Learning (ICML), Pittsburgh, PA, USA, 25–29 June 2006; pp. 369–376. [Google Scholar]
- Amodei, D.; Ananthanarayanan, S.; Anubhai, R.; Bai, J.; Battenberg, E.; Case, C.; Casper, J.; Catanzaro, B.; Cheng, Q.; Chen, G.; et al. Deep Speech 2: End-to-end speech recognition in English and Mandarin. In Proceedings of the 33rd International Conference on Machine Learning (ICML), New York, NY, USA, 19–24 June 2016; pp. 173–182. [Google Scholar]
- Chorowski, J.K.; Bahdanau, D.; Serdyuk, D.; Cho, K.; Bengio, Y. Attention-based models for speech recognition. In Advances in Neural Information Processing Systems; MIT Press: Cambridge, MA, USA, 2015; pp. 577–585. [Google Scholar]
- Chan, W.; Jaitly, N.; Le, Q.V.; Vinyals, O. Listen, attend and spell: A neural network for large vocabulary conversational speech recognition. In Proceedings of the IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), Shanghai, China, 20–25 March 2016; pp. 4960–4964. [Google Scholar]
- Baevski, A.; Schneider, S.; Cotterell, R.; Auli, M. wav2vec: Unsupervised pre-training for speech recognition. In Proceedings of the 36th International Conference on Machine Learning (ICML), Long Beach, CA, USA, 9–15 June 2019; pp. 902–911. [Google Scholar]
- Baevski, A.; Zhou, Y.; Mohamed, A.; Auli, M. wav2vec 2.0: A framework for self-supervised learning of speech representations. In Advances in Neural Information Processing Systems; Curran Associates, Inc.: Red Hook, NY, USA, 2020; Volume 33, pp. 12449–12460. [Google Scholar]
- Watanabe, S.; Hori, T.; Karita, S.; Hayashi, T.; Nishitoba, J.; Unno, Y.; Soplin, N.E.Y.; Heymann, J.; Wiesner, M.; Chen, N.; et al. ESPnet: End-to-end speech processing toolkit. In Proceedings of the Interspeech, Hyderabad, India, 2–6 September 2018; pp. 2207–2211. [Google Scholar]
- Hsu, W.N.; Bolte, B.; Tsai, Y.H.; Lakhotia, K.; Salakhutdinov, R.; Mohamed, A. HuBERT: Self-supervised speech representation learning by masked prediction of hidden units. IEEE/ACM Trans. Audio Speech Lang. Process. 2021, 29, 3451–3464. [Google Scholar] [CrossRef] [Scilit]
- Babu, A.; Wang, C.; Tjandra, A.; Lakhotia, K.; Xu, Q.; Goyal, N.; Singh, K.; von Platen, P.; Saraf, Y.; Pino, J.; et al. XLS-R: Self-supervised cross-lingual speech representation learning at scale. In Proceedings of the Interspeech, Incheon, Republic of Korea, 18–22 September 2022; pp. 4450–4454. [Google Scholar]
- Peng, Y.; Dalmia, S.; Li, I.E.; Watanabe, S. Branchformer: Parallel MLP-attention architectures are better than stacked for ASR. In Proceedings of the 39th International Conference on Machine Learning (ICML), Baltimore, MD, USA, 17–23 July 2022; pp. 17714–17728. [Google Scholar]
- Kim, K.; Peng, Y.; Huang, S.J.; Peng, Y.; Pan, J.; Sridhar, P.; Han, K.J.; Watanabe, S. E-Branchformer: Branchformer with Enhanced Merging for Speech Recognition. In Proceedings of the IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), Rhodes Island, Greece, 4–10 June 2023; pp. 10014–10018. [Google Scholar]
- Yao, Z.; Wu, D.; Wang, X.; Kang, W.; Kuang, F.; Yang, Y.; Jin, Z.; Lin, L.; Povey, D. Zipformer: A Faster and Better Encoder for Automatic Speech Recognition. In Proceedings of the International Conference on Learning Representations (ICLR), Vienna, Austria, 7–11 May 2024. [Google Scholar]
- Dong, Y.; Cordonnier, J.B.; Loukas, A. Attention is not all you need: Pure attention loses rank doubly exponentially with depth. In Proceedings of the 38th International Conference on Machine Learning (ICML), Virtual Event, 18–24 July 2021; pp. 2793–2803. [Google Scholar]
- Tian, J.; Yu, J.; Weng, C.; Yu, D.; Watanabe, S. Bayes risk CTC: Controllable CTC alignment in sequence-to-sequence tasks. In Proceedings of the International Conference on Learning Representations (ICLR), Kigali, Rwanda, 1–5 May 2023. [Google Scholar]
- Nozaki, J.; Watanabe, S. Relaxing the conditional independence assumption of CTC-based ASR by conditioning on intermediate predictions. In Proceedings of the Interspeech, Brno, Czech Republic, 30 August–3 September 2021; pp. 2092–2096. [Google Scholar]
- Pasad, A.; Chou, J.C.; Livescu, K. Layer-wise analysis of a self-supervised speech representation model. In Proceedings of the IEEE Automatic Speech Recognition and Understanding Workshop (ASRU), Cartagena, Colombia, 13–17 December 2021; pp. 1024–1031. [Google Scholar]
- Gulati, A.; Qin, J.; Chiu, C.C.; Parmar, N.; Zhang, Y.; Yu, J.; Han, W.; Wang, S.; Zhang, Z.; Wu, Y.; et al. Conformer: Convolution-augmented transformer for speech recognition. In Proceedings of the Interspeech, Shanghai, China, 25–29 October 2020; pp. 5036–5040. [Google Scholar]
- Hsu, W.N.; Sriram, A.; Baevski, A.; Likhomanenko, T.; Xu, Q.; Pratap, V.; Kahn, J.; Lee, A.; Collobert, R.; Synnaeve, G.; et al. Robust wav2vec 2.0: Analyzing domain shift in self-supervised pre-training. In Proceedings of the Interspeech, Brno, Czech Republic, 30 August–3 September 2021; pp. 4533–4537. [Google Scholar]
- Kriman, S.; Beliaev, S.; Ginsburg, B.; Huang, B.; Kuchaiev, O.; Lavrukhin, V.; Leary, R.; Li, J.; Zhang, Y. QuartzNet: Deep acoustic models with 1D time-channel separable convolutions. In Proceedings of the IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), Barcelona, Spain, 4–8 May 2020; pp. 6124–6128. [Google Scholar]
- Wu, F.; Fan, A.; Baevski, A.; Dauphin, Y.N.; Auli, M. Pay less attention with lightweight and dynamic convolutions. In Proceedings of the International Conference on Learning Representations (ICLR), New Orleans, LA, USA, 6–9 May 2019. [Google Scholar]
- Chollet, F. Xception: Deep learning with depthwise separable convolutions. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Honolulu, HI, USA, 21–26 July 2017; pp. 1251–1258. [Google Scholar]
- Scherer, D.; Müller, A.; Behnke, S. Evaluation of pooling operations in convolutional architectures for object recognition. In Proceedings of the International Conference on Artificial Neural Networks (ICANN), Thessaloniki, Greece, 15–18 September 2010; pp. 92–101. [Google Scholar]
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, L.; Gomez, A.N.; Kaiser, Ł.; Polosukhin, I. Attention is all you need. In Advances in Neural Information Processing Systems; Curran Associates, Inc.: Long Beach, CA, USA, 2017; Volume 30. [Google Scholar]
- Liu, C.; Ni, R.; Zhou, L.; Hou, C.Y. Deep learning model for automatic speech editing based on multi-acoustic feature fusion. J. Chin. Comput. Syst. 2023, 44, 1713–1719. [Google Scholar]
- Arevalo, J.; Solorio, T.; Montes-y-Gómez, M.; González, F.A. Gated multimodal units for information fusion. In Proceedings of the ICLR 2017 Workshop, Toulon, France, 24–26 April 2017. [Google Scholar]
- Dauphin, Y.N.; Fan, A.; Auli, M.; Grangier, D. Language modeling with gated convolutional networks. In Proceedings of the 34th International Conference on Machine Learning (ICML), Sydney, Australia, 6–11 August 2017; pp. 933–941. [Google Scholar]
- Bu, H.; Du, J.; Na, X.; Wu, B.; Zheng, H. AISHELL-1: An open-source Mandarin speech corpus and a speech recognition baseline. In Proceedings of the 20th Conference of the Oriental Chapter of the International Coordinating Committee on Speech Databases and Speech I/O Systems and Assessment (O-COCOSDA), Seoul, Republic of Korea, 1–3 November 2017; pp. 1–5. [Google Scholar]
- Surfingtech. Free ST Chinese Mandarin Corpus. Available online: http://www.openslr.org/38/ (accessed on 7 February 2025).
- Loshchilov, I.; Hutter, F. Decoupled weight decay regularization. In Proceedings of the International Conference on Learning Representations (ICLR), New Orleans, LA, USA, 6–9 May 2019. [Google Scholar]
- Paszke, A.; Gross, S.; Massa, F.; Lerer, A.; Bradbury, J.; Chanan, G.; Killeen, T.; Lin, Z.; Gimelshein, N.; Antiga, L.; et al. PyTorch: An imperative style, high-performance deep learning library. In Advances in Neural Information Processing Systems; Curran Associates, Inc.: Vancouver, BC, Canada, 2019; Volume 32. [Google Scholar]
- Yao, Z.; Wu, D.; Wang, X.; Zhang, B.; Yu, F.; Yang, C.; Peng, Z.; Chen, X.; Xie, L.; Lei, X. WeNet: Production oriented streaming and non-streaming end-to-end speech recognition toolkit. In Proceedings of the Interspeech, Brno, Czech Republic, 30 August–3 September 2021; pp. 4054–4058. [Google Scholar]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.