


Abstract
Wind speed prediction is very important in the field of wind power generation technology. It is helpful for increasing the quantity and quality of generated wind power from wind farms. By using univariate wind speed time series, this paper proposes a hybrid wind speed prediction model based on Autoregressive Moving Average-Support Vector Regression (ARMA-SVR) and error compensation. First, to explore the balance between the computation cost and the sufficiency of the input features, the characteristics of ARMA are employed to determine the number of historical wind speeds for the prediction model. According to the selected number of input features, the original data are divided into multiple groups that can be used to train the SVR-based wind speed prediction model. Furthermore, in order to compensate for the time lag introduced by the frequent and sharp fluctuations in natural wind speed, a novel Extreme Learning Machine (ELM)-based error correction technique is developed to decrease the deviations between the predicted wind speed and its real values. By this means, more accurate wind speed prediction results can be obtained. Finally, verification studies are conducted by using real data collected from actual wind farms. Comparison results demonstrate that the proposed method can achieve better prediction results than traditional approaches.
1. Introduction
Since the beginning of the 21st century, people’s demand for energy has become stronger and stronger [1]. However, coal, oil, natural gas and other non-renewable resources still occupy the main part of the world energy market [2]. The burning of these fossil fuels will release greenhouse gases and threaten the environment. In order to solve the energy crisis and protect the environment, people are trying to develop new energy sources [3]. Nowadays, as one of the fastest developing new technologies in recent years, wind power generation technology is attracting widespread attention [4].
Wind power is a clean, renewable and pollution-free energy source [5]. However, as a natural resource, wind power has the characteristics of instability and uncertainty. Wind speed changes frequently, which brings great challenges to the stability of the wind power generation system and increases the operation and maintenance costs of the power plant [6].
In order to solve the instability problem in wind power generation, one of the most effective solutions is wind speed prediction [7]. As a cheap and effective method, it also plays a positive role in reducing operating costs and improving wind power competitiveness [8]. Through predicting the wind speed, it can guide the power scheme to adjust the power generation plan reasonably [9], change the torque of a wind turbine to maximize the use of wind power [10], protect the safety of the wind turbines so that the wind farm can use more advanced materials [11,12,13], and optimize the layout of wind turbines and improve the economic benefits of wind farms [14].
Many methods have been proposed for wind speed prediction. These methods can be divided into two categories: linear strategies and nonlinear approaches. Traditional linear methods use the linear combination of historical values to predict future wind speeds, such as with Autoregressive Moving Average (ARMA) [15]. Since these methods assume the relationship between historical wind speeds and future ones are linear and ignore the nonlinear characteristics, the prediction accuracy is not optimal [16]. With the rise of artificial intelligence [17], more and more nonlinear methods have been studied, such as Backpropagation Neural Network (BPNN) [18], Convolution Neural Network (CNN) [19], Support Vector Machine (SVM) [20], Extreme Learning Machine (ELM) [21], Long-short Term Memory Network (LSTM) [22], and the hybrid model combining multiple methods [23]. These nonlinear methods can accept more input features and can achieve more accurate predictions by selecting appropriate activation functions and hyperparameters.
However, to reduce the operating costs, some wind farms only collect and save wind speed information for wind speed forcasting. They ignore other factors affecting wind speed, such as topographic features, temperature, pressure, humidity and so on [24]. This causes the original data to be a univariate time series containing historical wind speeds only. Many nonlinear methods, such as ANN, SVR, ELM, etc., need sufficient inputs to ensure the accuracy of the prediction results. For univariate time series, if we want to achieve better prediction accuracy by using machine learning methods with a relatively low computation cost, we may need to divide the sequence into multiple segments and choose the appropriate number of data as the input and output for constructing a training set. That is, an appropriate number of historical wind speed points should be used to predict future values. Moreover, in the forcast methods based on time series, there is always a time lag between the predicted wind speed and actual values due to the rapid changes in natural wind speeds and time delays in the original wind data collection. This prediction lag will greatly reduce the accuracy of the wind speed forecast results [25].
Therefore, to find the optimal number of historical input data for a prediction model and alleviate the forecast time lag phenomenon, this study proposes a novel wind speed prediciton method to improve the prediction accuracy by combining the ARMA-SVR model and an error compensation technique. First, the ARMA model of the raw wind speed data is built, and the Partial Autocorrelation Coefficient (PAC) p of the model is calculated by using Akaike Information Criterion (AIC). Second, the p value is used as the basis for dividing the data set to train SVR for the wind speed prediction model. Then, the error set can be constructed by subtracting the predicted value from the true value. The same data preprocessing method for raw wind speed is utilized for the error time series to obtain the training set for the lag compensation model. Finally, the ELM is employed as the time lag correction model to give the predicted error. By adding the raw wind speed prediction result and the error prediction result, the final wind speed prediction result can be obtained. Through a comparison with SVR and BPNN, the ARMA-SVR-ELM model in this paper has a better prediction effect. The major contributions of this paper can be summarized as follows:
- For univariate time series forecasting, in order to explore the balance between the computation cost and the sufficiency of input features, this paper uses the parameters of the ARMA model which can be employed as the basis from which to select the optimal division data as the input of the SVR model.
- Through constructing the error dataset, an ELM-based time lag compensation technique is designed to mine the effective information of the error time series. By this way, the forecast lag phenomenon can be alleviated effectively.
- By combining the ARMA-SVR model and the error correction approach, a novel wind speed prediction approach is proposed to improve the prediction results. Simulation results show the proposed method can achieve better accuracy than traditional methods.
2. Mathematical Models
This paper mainly uses ARMA, SVR and ELM models, which will be briefly described in this section.
2.1. The ARMA Model
The ARMA (p, q) model is one of the earliest models used for time series prediction [26]. It includes two parts: the Autoregressive(AR) model and the Moving Average(MA) model. The ARMA model can be described as follows
where is wind speed time series.
The ARMA model describes the relationship between current value, historical error and historical value. Equation (1) shows that the current value is composed of a linear combination of p historical values and q historical errors. The p and q are selected by AIC. The p value means that if every p data is taken as a group, the internal correlation of this group is very strong. Therefore, it is very reasonable to select p as the basis for dividing the univariate series.
2.2. The SVR Model
The SVR model can map low dimensional nonlinear problems to high dimensional space [27], and transform them into linear problems. The optimal hyperplane can be found as follows
In this paper, the Radial Basis Function (RBF) is chosen as the kernel function. The RBF can map samples to a higher dimensional space, which can better handle nonlinear wind speed prediction problems. The RBF is shown as follows
where is the Euclidean distance (L2 norm) of x and , and controls the range of influence of the RBF. The larger the is, the larger the influence range of the RBF.
To find the the optimal hyperplane , hyper parameter and b need to be optimized. Therefore, the SVR model minimizes the following constrained condition
The SVR model can achieve a good prediction effect due to its ability to describe the nonlinear relationship between an input and an output [28]. Therefore, this paper chooses the SVR model to predict future wind speed.
2.3. The ELM Model
The ELM is a single hidden layer network model that uses random input layer weights and deviations and a generalized inverse matrix theory to calculate the output layer weights. Its output is as follows
ELM is not sensitive to the selection of parameters, and it has a fast training response and high accuracy [29]. Therefore, this paper uses the ELM model to predict errors.
2.4. Model Evaluation Index
This paper uses Root Mean Square Error (RMSE) and Coefficient of Determination () to evaluate the prediction effect of the model
From Equations (7) and (8), N is the number of samples, and represent the ith real value and the ith estimated value of the wind speed series, respectively, and is the average value of the samples.
3. The Proposed Method
In order to better predict univariate time series, this paper proposes an ARMA-SVR wind speed prediction method based on ELM error compensation (ARMA-SVR-ELM hybrid model).
The data used in this paper are the univariate series, which means the data only has wind speed without other features. In order to enable SVR and ELM models to make full use of the original data with appropriate computational cost, this paper uses the ARMA model to find the relationship between each data point in the original univariate sequence, and it takes several data with strong correlation as a new set of sequences. As described in Section 2, the ARMA model can effectively handle the time univariate series. It can be seen from Equation (1) that in the ARMA model, the current value is related to the partial historical value and the historical error value. These values have a relatively strong correlation. Therefore, it is reasonable to use each group of sequences that has strong correlation as the training parameters of SVR to predict future wind speed. In this new set of sequences, the last value is used as the output, and all the previous data are used as the inputs. By this means, the original data is divided into multiple groups, and all of them are used to train the SVR and ELM models. Since the ARMA model is often used to deal with univariate time series, the ARMA model’s PAC reflects the relationship between the current value and multiple historical values with strong correlation. Therefore, it is very reasonable to divide the original data into multiple groups of sequences based on the p value obtained by the ARMA method.
This paper uses the divided data to train the SVR model to predict wind speed directly. Although the overall effect looks good, the fitting effect is not ideal in some periods when the wind speed changes rapidly. In order to deal with this and further improve the wind speed prediction accuracy, the prediction error was collected to develop the error correction technique in our study. The collected error data is still a univariate time series. Therefore, the same ARMA processing method as that of the original wind speed data was adopted, and the divided data was used to train the ELM model for error prediction. By this means, the error value of the future wind speed was obtained. When getting the wind speed prediction value and the error prediction value, the final wind speed prediction value can be obtained by adding these two prediction values. This process is called the “wind speed prediction based on error compensation technique” in our study.
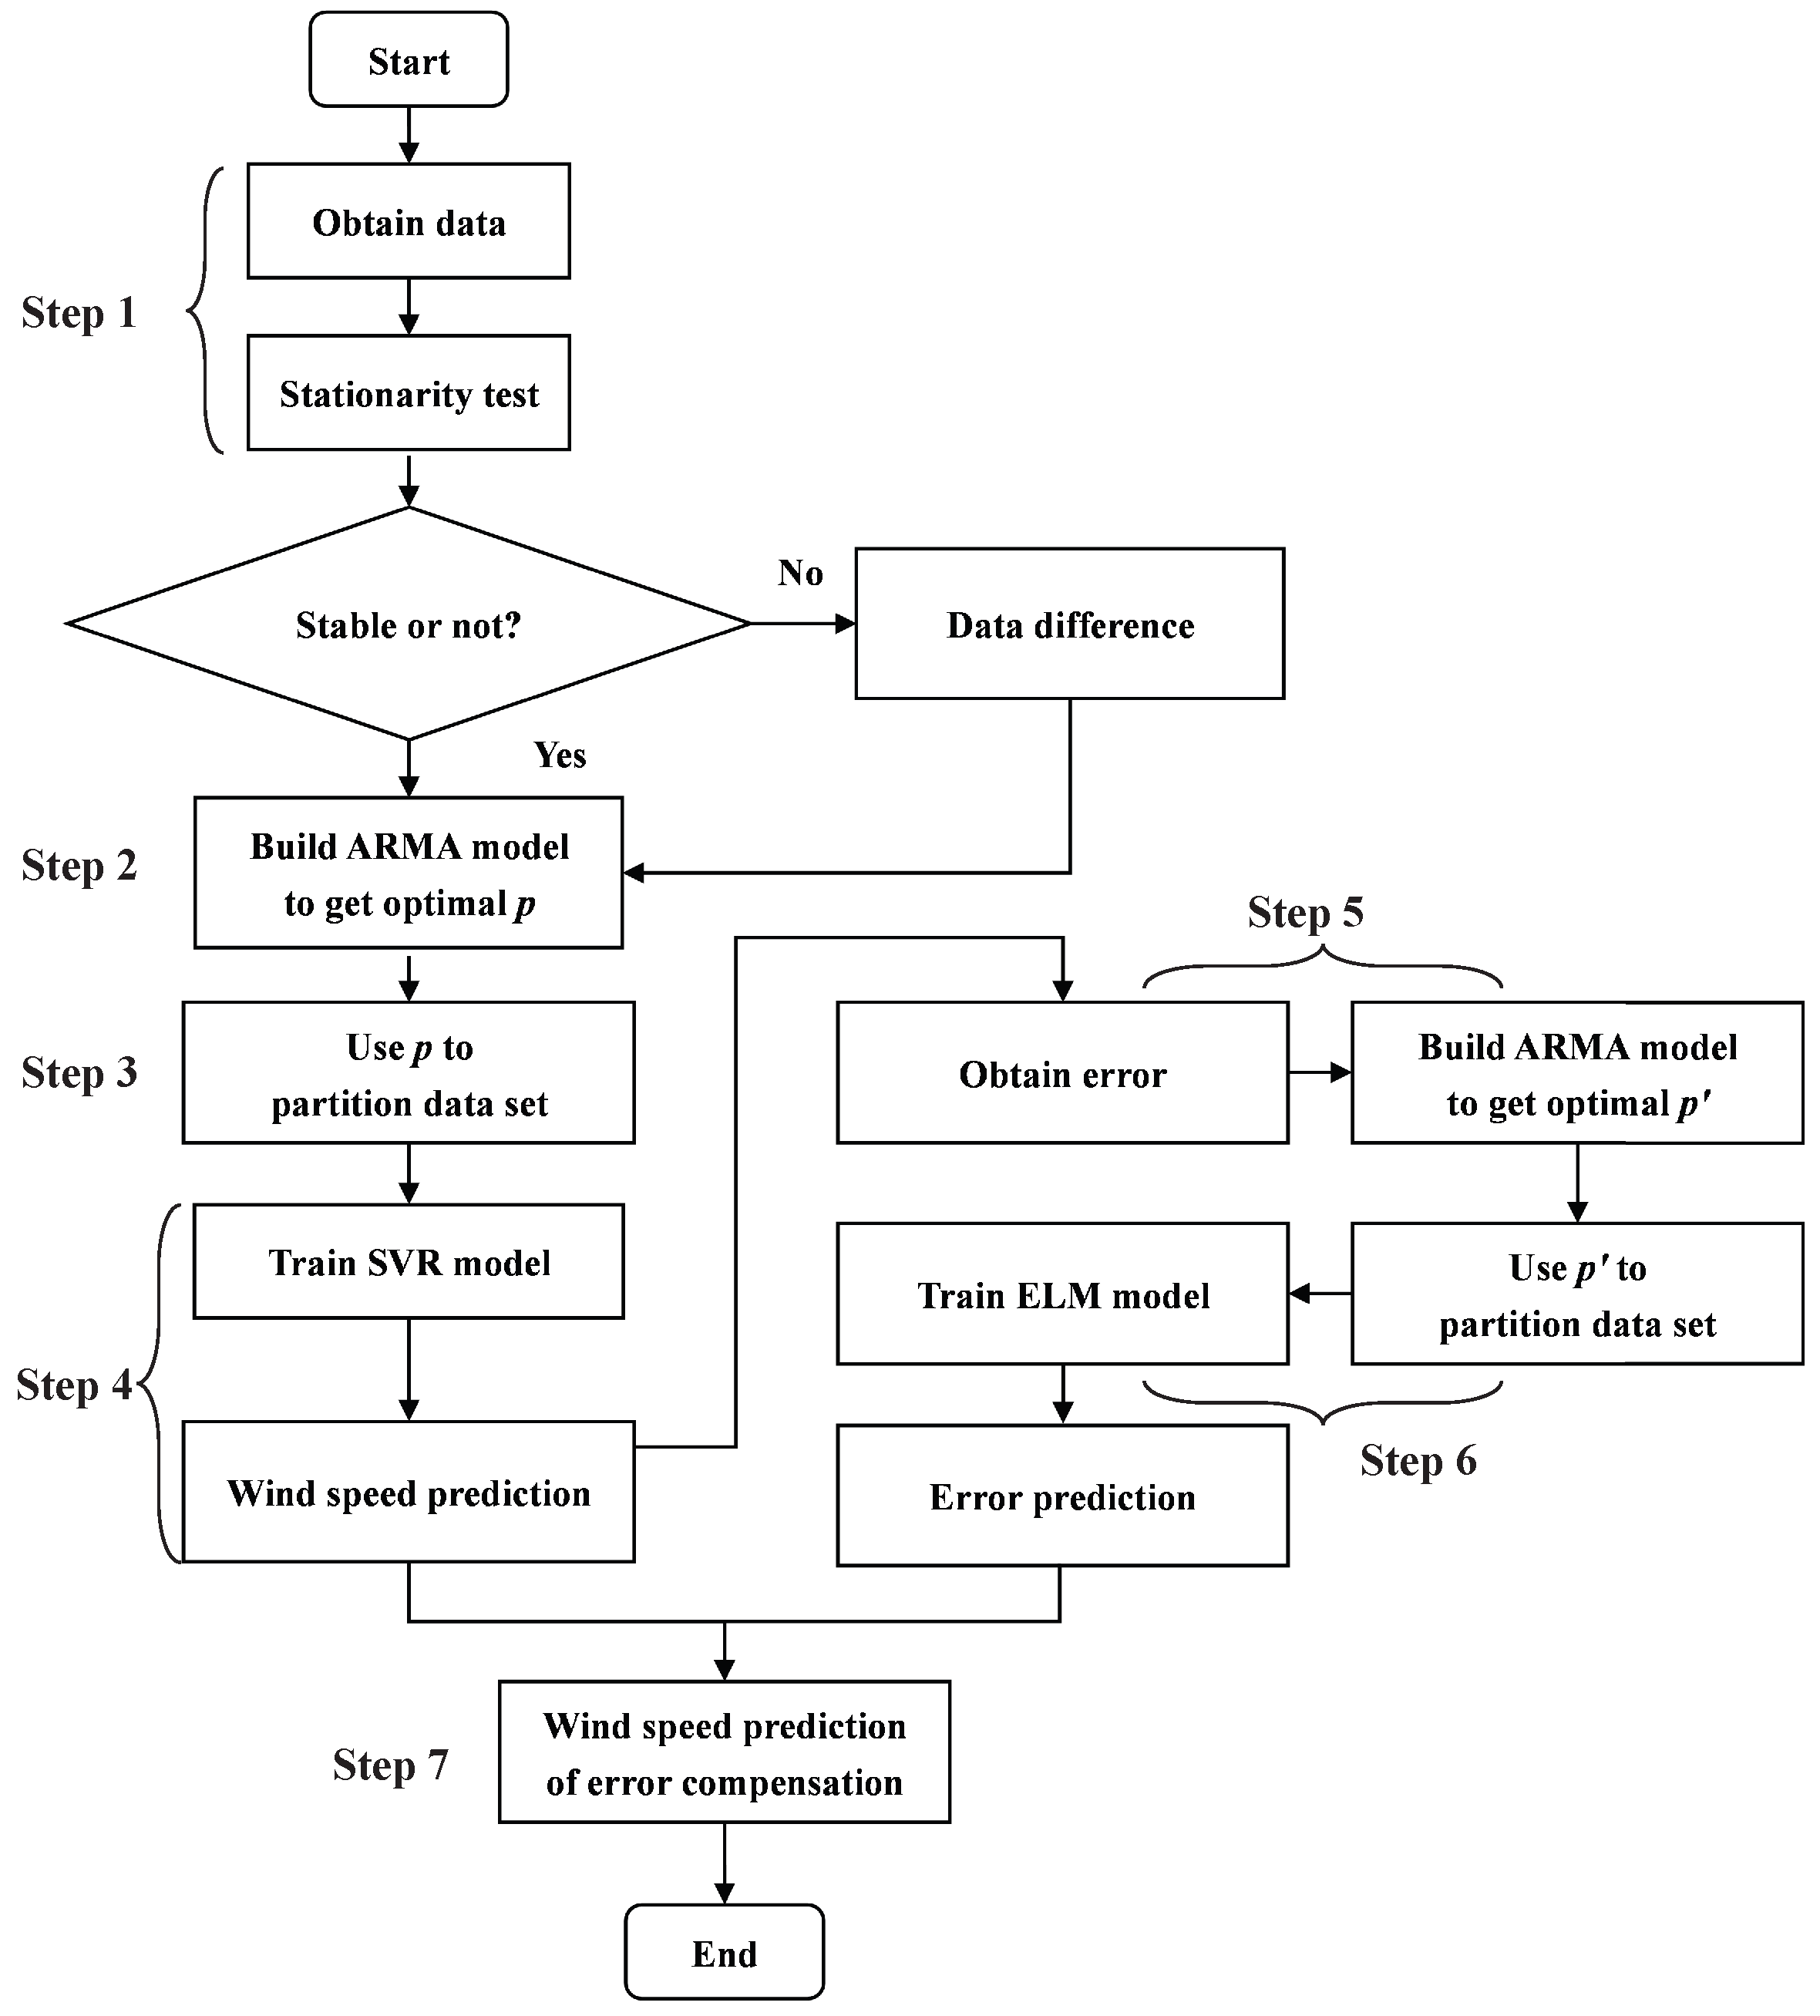
The flow chart of the proposed method is shown as Figure 1 and the detailed description is as follows.
Figure 1.
The Flow Chart of The Experiment.
- Step 1: Data Processing
The ARMA model is often used for time series prediction, and it requires that the input data must be a stationary series. The definition of a stationary sequence is as follows
where represents the autocorrelation coefficients at time t and time .
Equation (9) shows that the expectation and variance of the stationary sequence do not change with time. Due to the influence of temperature, pressure and many other factors, there are few stable wind speed time series in nature. This leads to the fact that the data collected in many cases cannot be used directly and must be preprocessed. In order to make the sequence stable, this paper uses differential processing, and the Augmented Dickey-Fuller (ADF) test is used to check whether the differenced sequence is stable. After that, the Autocorrelation Functions (ACF) and the Partial Autocorrelation Functions (PACF) diagrams are calculated to determine the value range of the number of input features.
In Step 1, the ADF test is used to test the stationarity of the sequence by checking whether the characteristic root of the sequence is within the unit circle.
- Step 2: ARMA Modeling
This step uses the differential data to establish the ARMA (p, q) model, and then AIC criteria are used to find the optimal p and q. In the above-mentioned model, p represents Partical Autocorrelation Coefficient (PAC) and q represents Autocorrelation Coefficient (AC).
In Step 2, AIC is often used to evaluate the quality of the regression model. In this paper, it is used for determining the optimal AC and PAC of the ARMA(p, q) model. The AIC can be described as follows
where SSR is Sum of Squared Residuals, n is the number of samples, and k is the number of unknown parameters.
- Step 3: Data Partitioning
After finding the optimal p, we use it to partition the data. With this specific method, starting from the data at the first moment, each p data is a group, where the first data are the inputs, and the pth data is the output. That is, the first data are used as the features to predict the pth value. Then, we start with the second data set and repeat the previous step until all the data are divided. This process can be described as follows
The principle for this is that p represents the correlation of the data in the original sequence, which can maximize the utilization of the data without losing too much machine performance.
- Step 4: Wind Speed Prediction
The partitioned data are used to train the SVR model to predict the wind speed. In this step, the training data and the test data are from Step 3, and the choice of kernel function for the SVR model is RBF.
- Step 5: Error Data Processing and Modeling
The trained SVR model obtained in Step 4 is used to predict the training set, and then the predicted value of the original data can be obtained. The error sequence can be obtained by subtracting the predicted value from the original data. The processing and modeling method of the error sequence is the same as that of the raw data in Step 1 and Step 2. The stationarity of the sequence is detected first. Then, its ACF and PACF images are drawn, and the ARMA model is built to find the optimal p and q of the error set by using the AIC criteria.
- Step 6: Error Data Partitioning and Predicting
The method of dividing error data is the same as in Step 3: the data are divided into multiple groups by using the p value obtained in Step 5. The first numbers of each group are regarded as the inputs, and the pth data is regarded as the output. Then, the partitioned data are used to train the ELM model to predict the future error.
- Step 7: Get the Final Wind Speed Prediction Result
In Step 4, we get the wind speed prediction result, and the error prediction result is obtained in Step 6. In this step, we need to add them, and then the final wind speed prediction result can be obtained.
4. Experiment
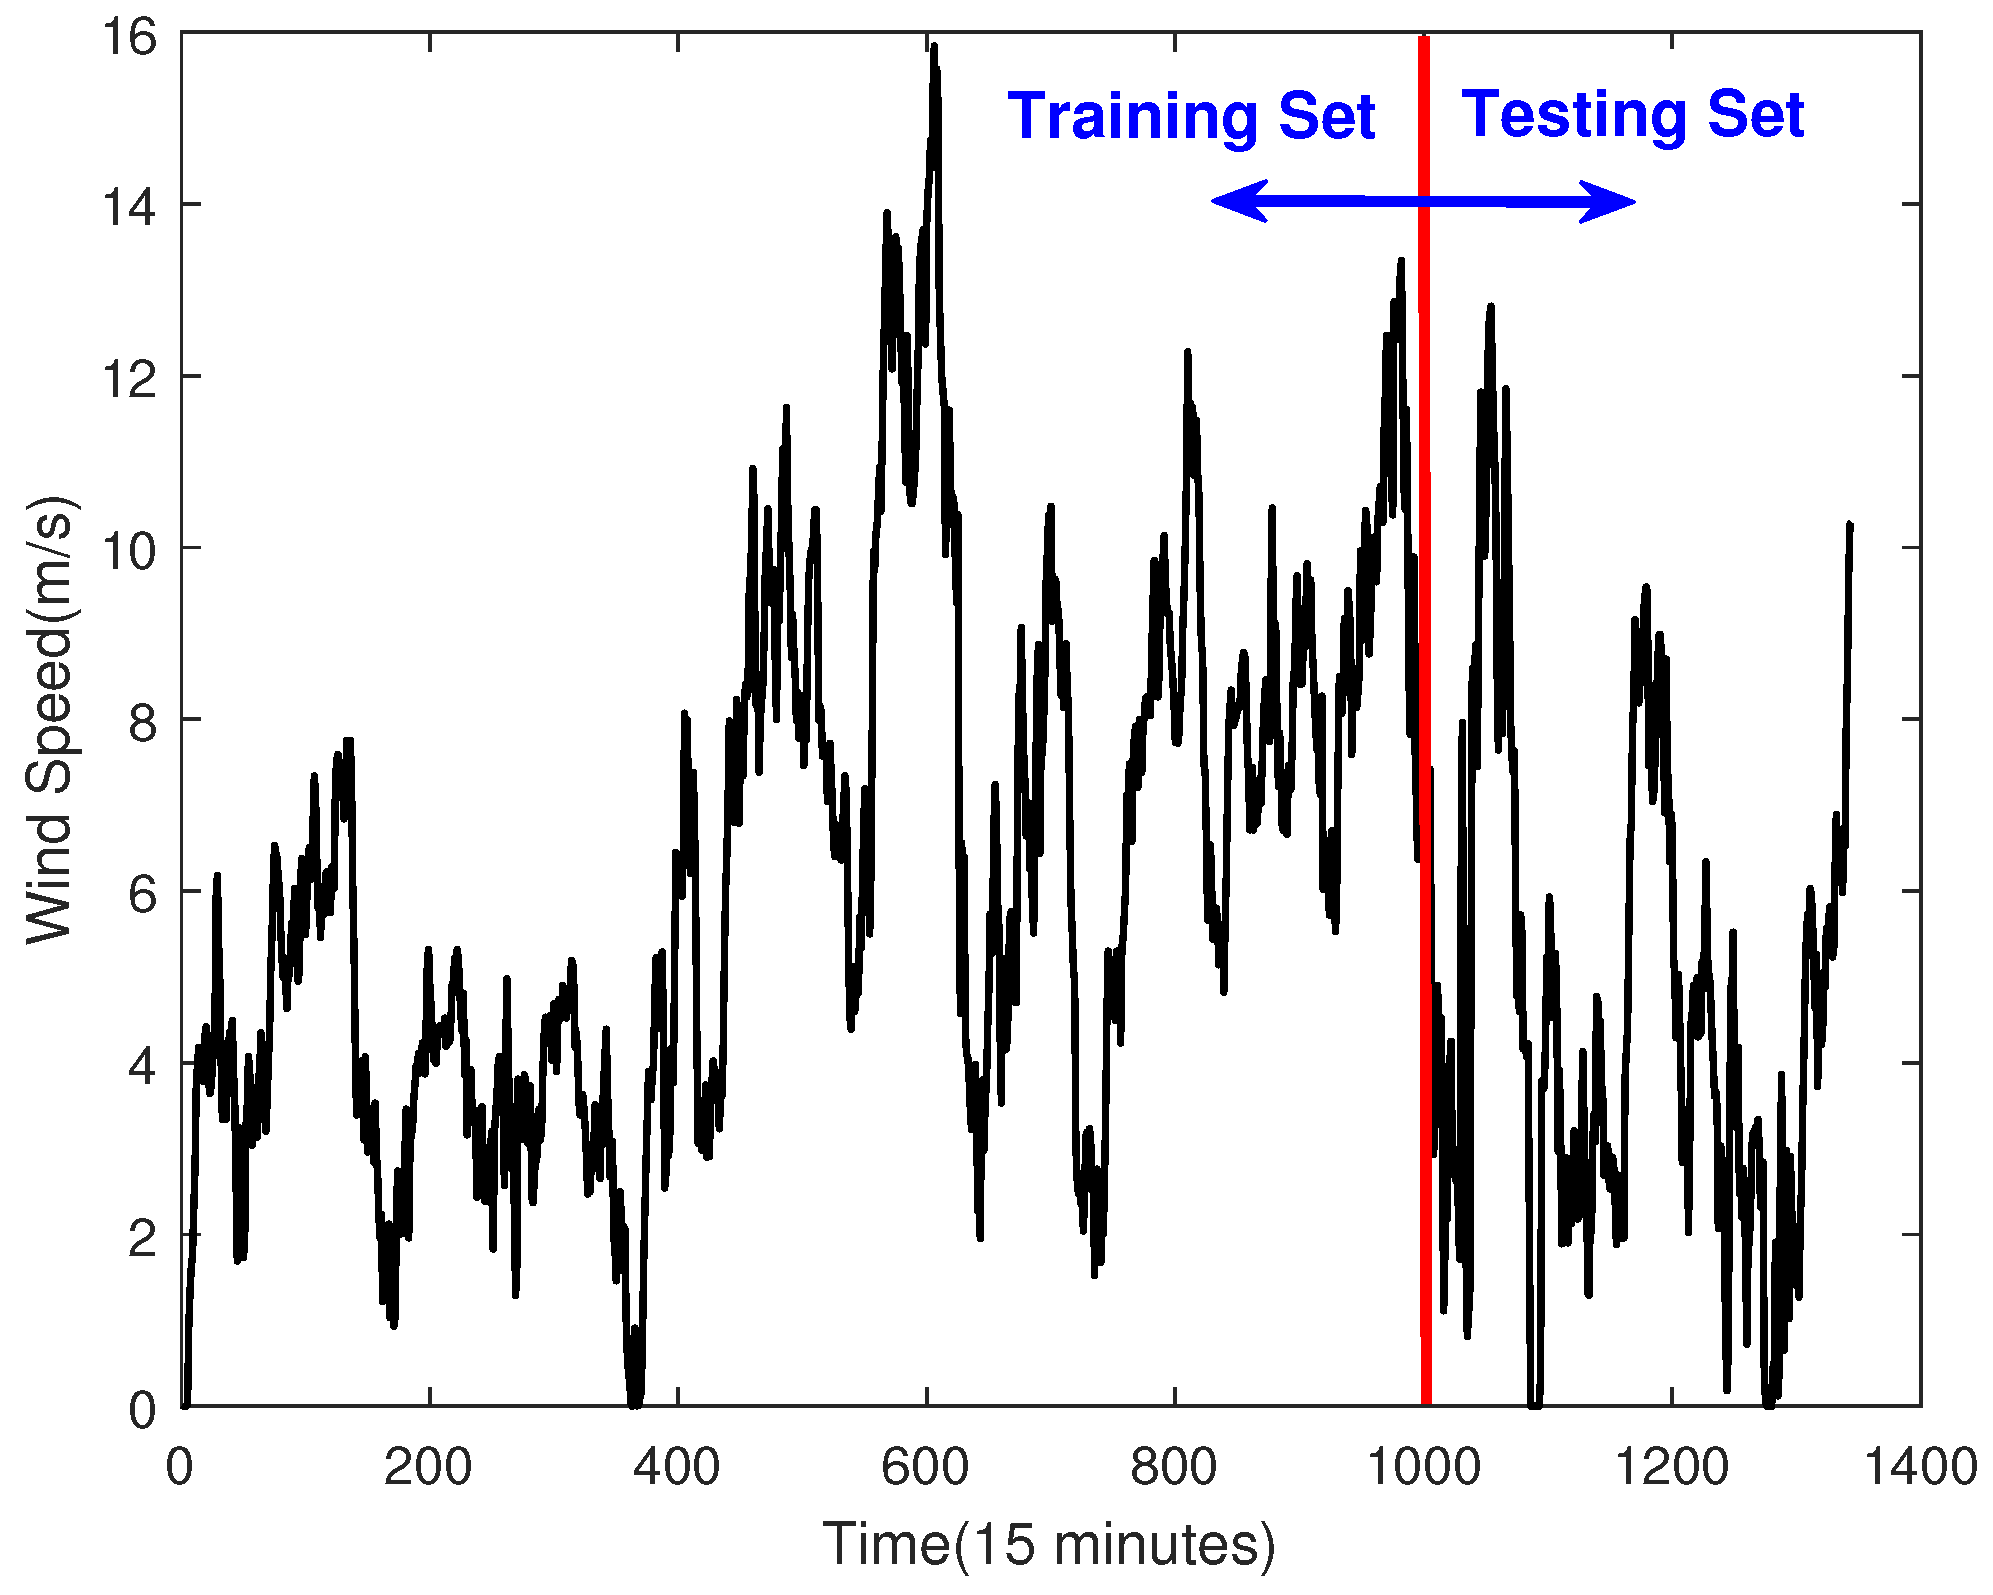
This section mainly introduces the results and discussions of the experiment. The raw wind speed data from a wind farm in China is shown in Figure 2. Among them, the data are recorded every 15 min, a total of 1344 data points are selected, the first 1000 data points are used as the training set, and the remaining data are used as the testing set. The experiment was tested on a PC with AMD Ryzen 5800H, NVDIA RTX 3070 Laptop and 16 GB memory. The following is the experimental result.
Figure 2.
The Raw Data.
4.1. Experiment Steps of Wind Speed Prediction
4.1.1. Data Processing
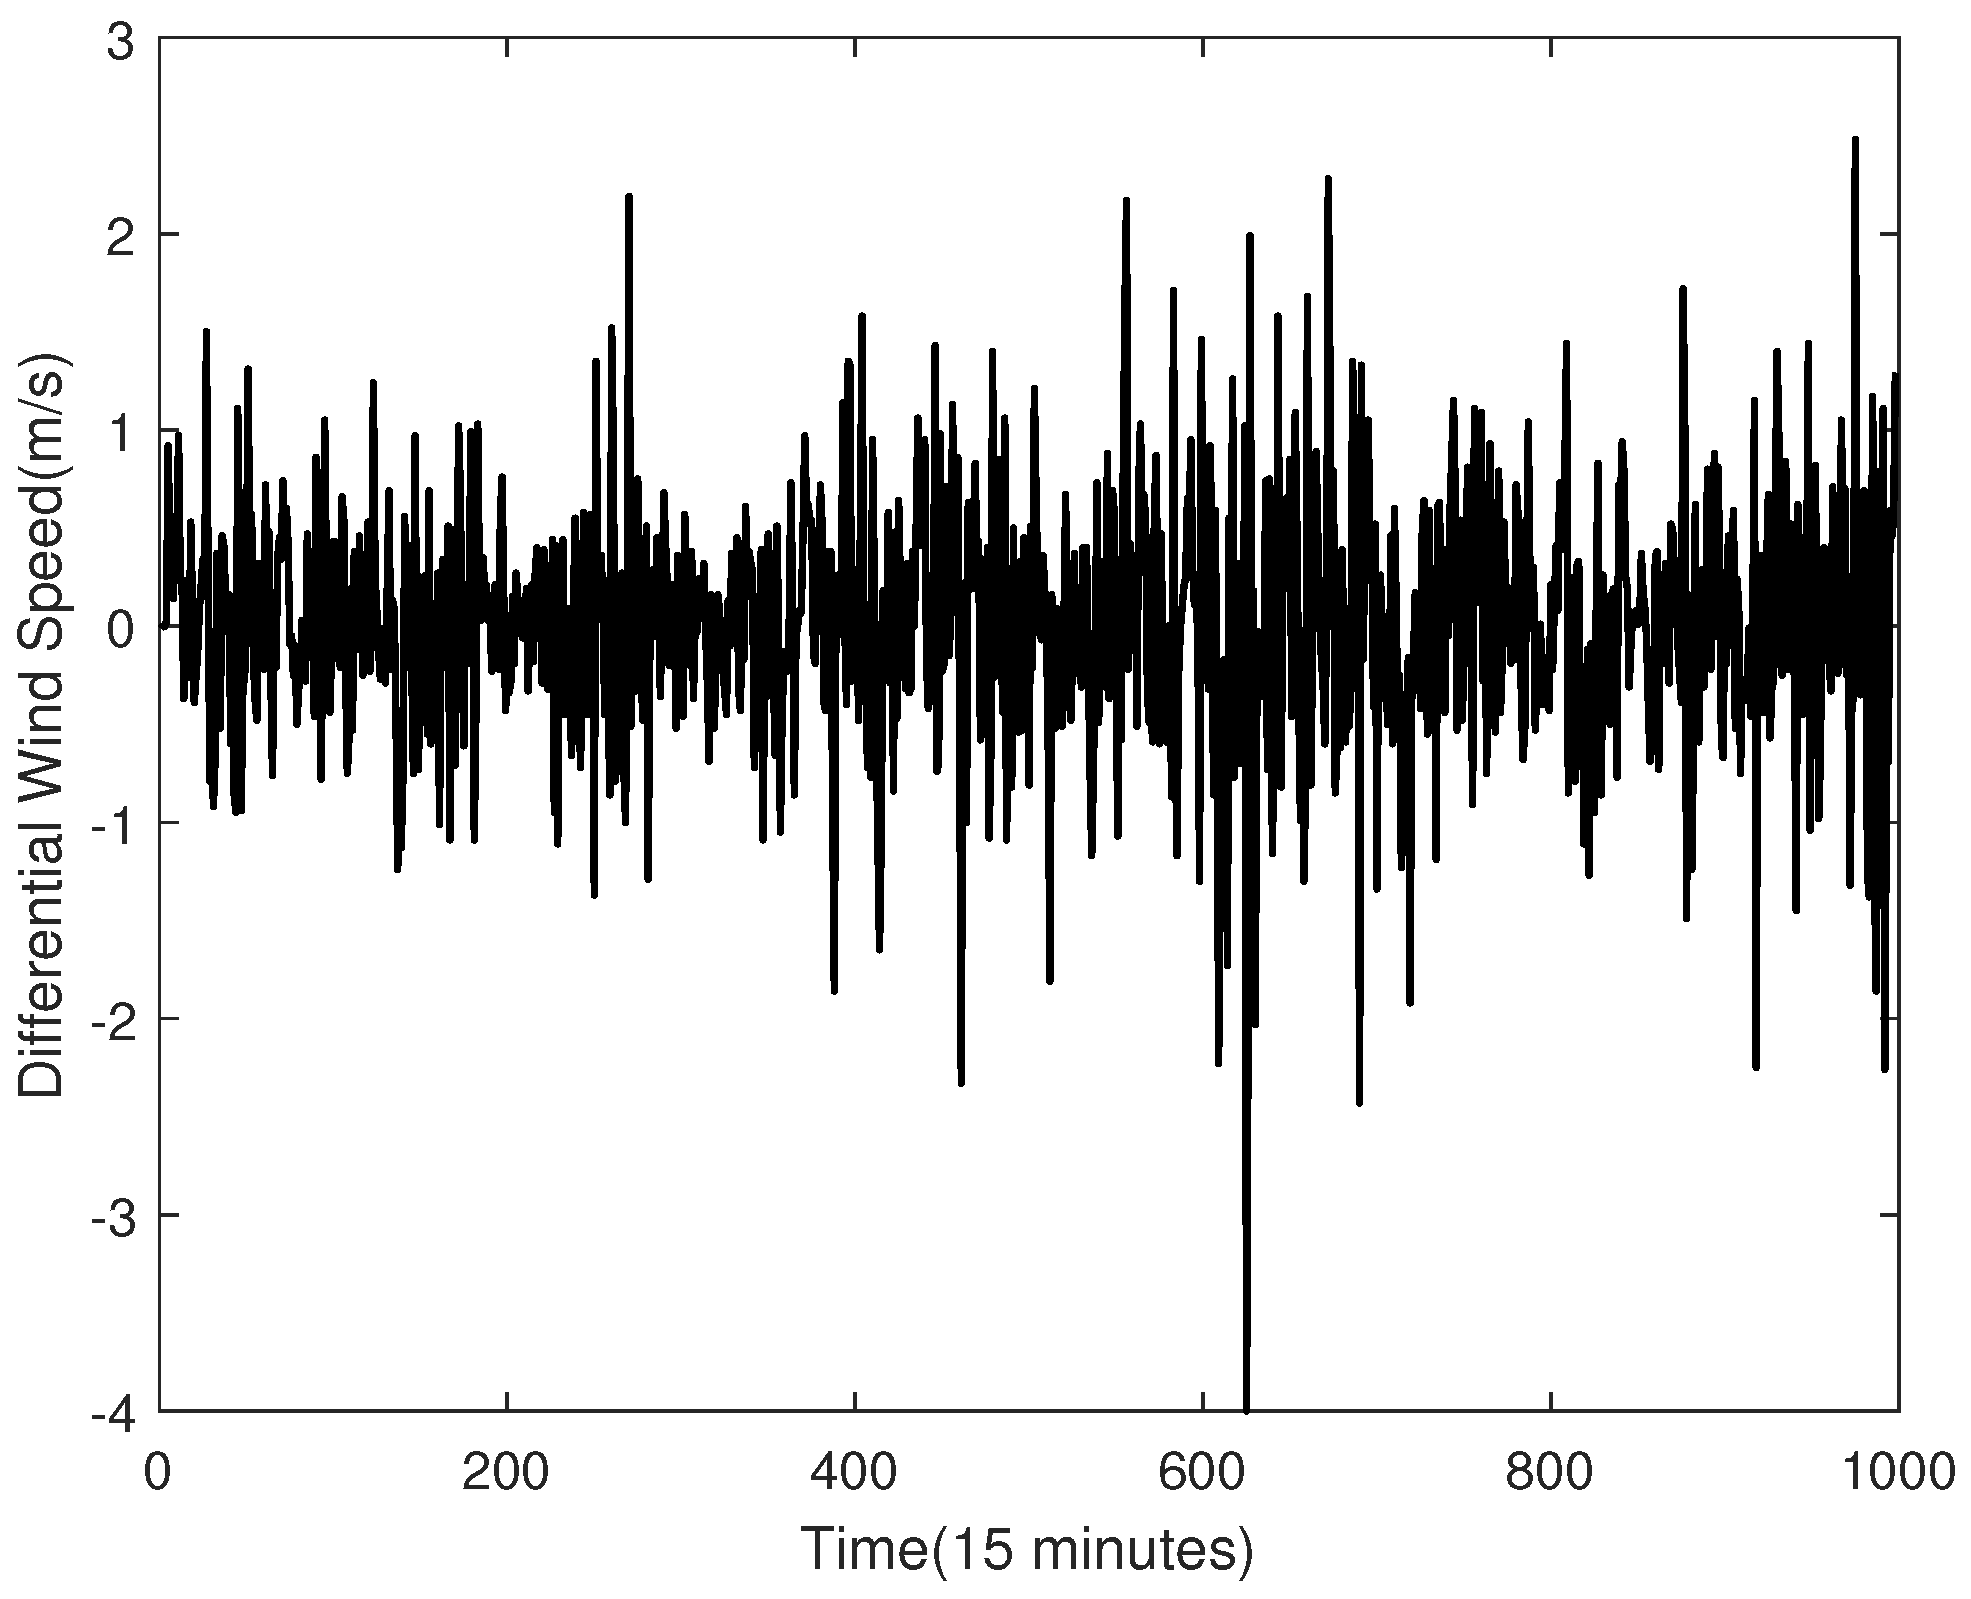
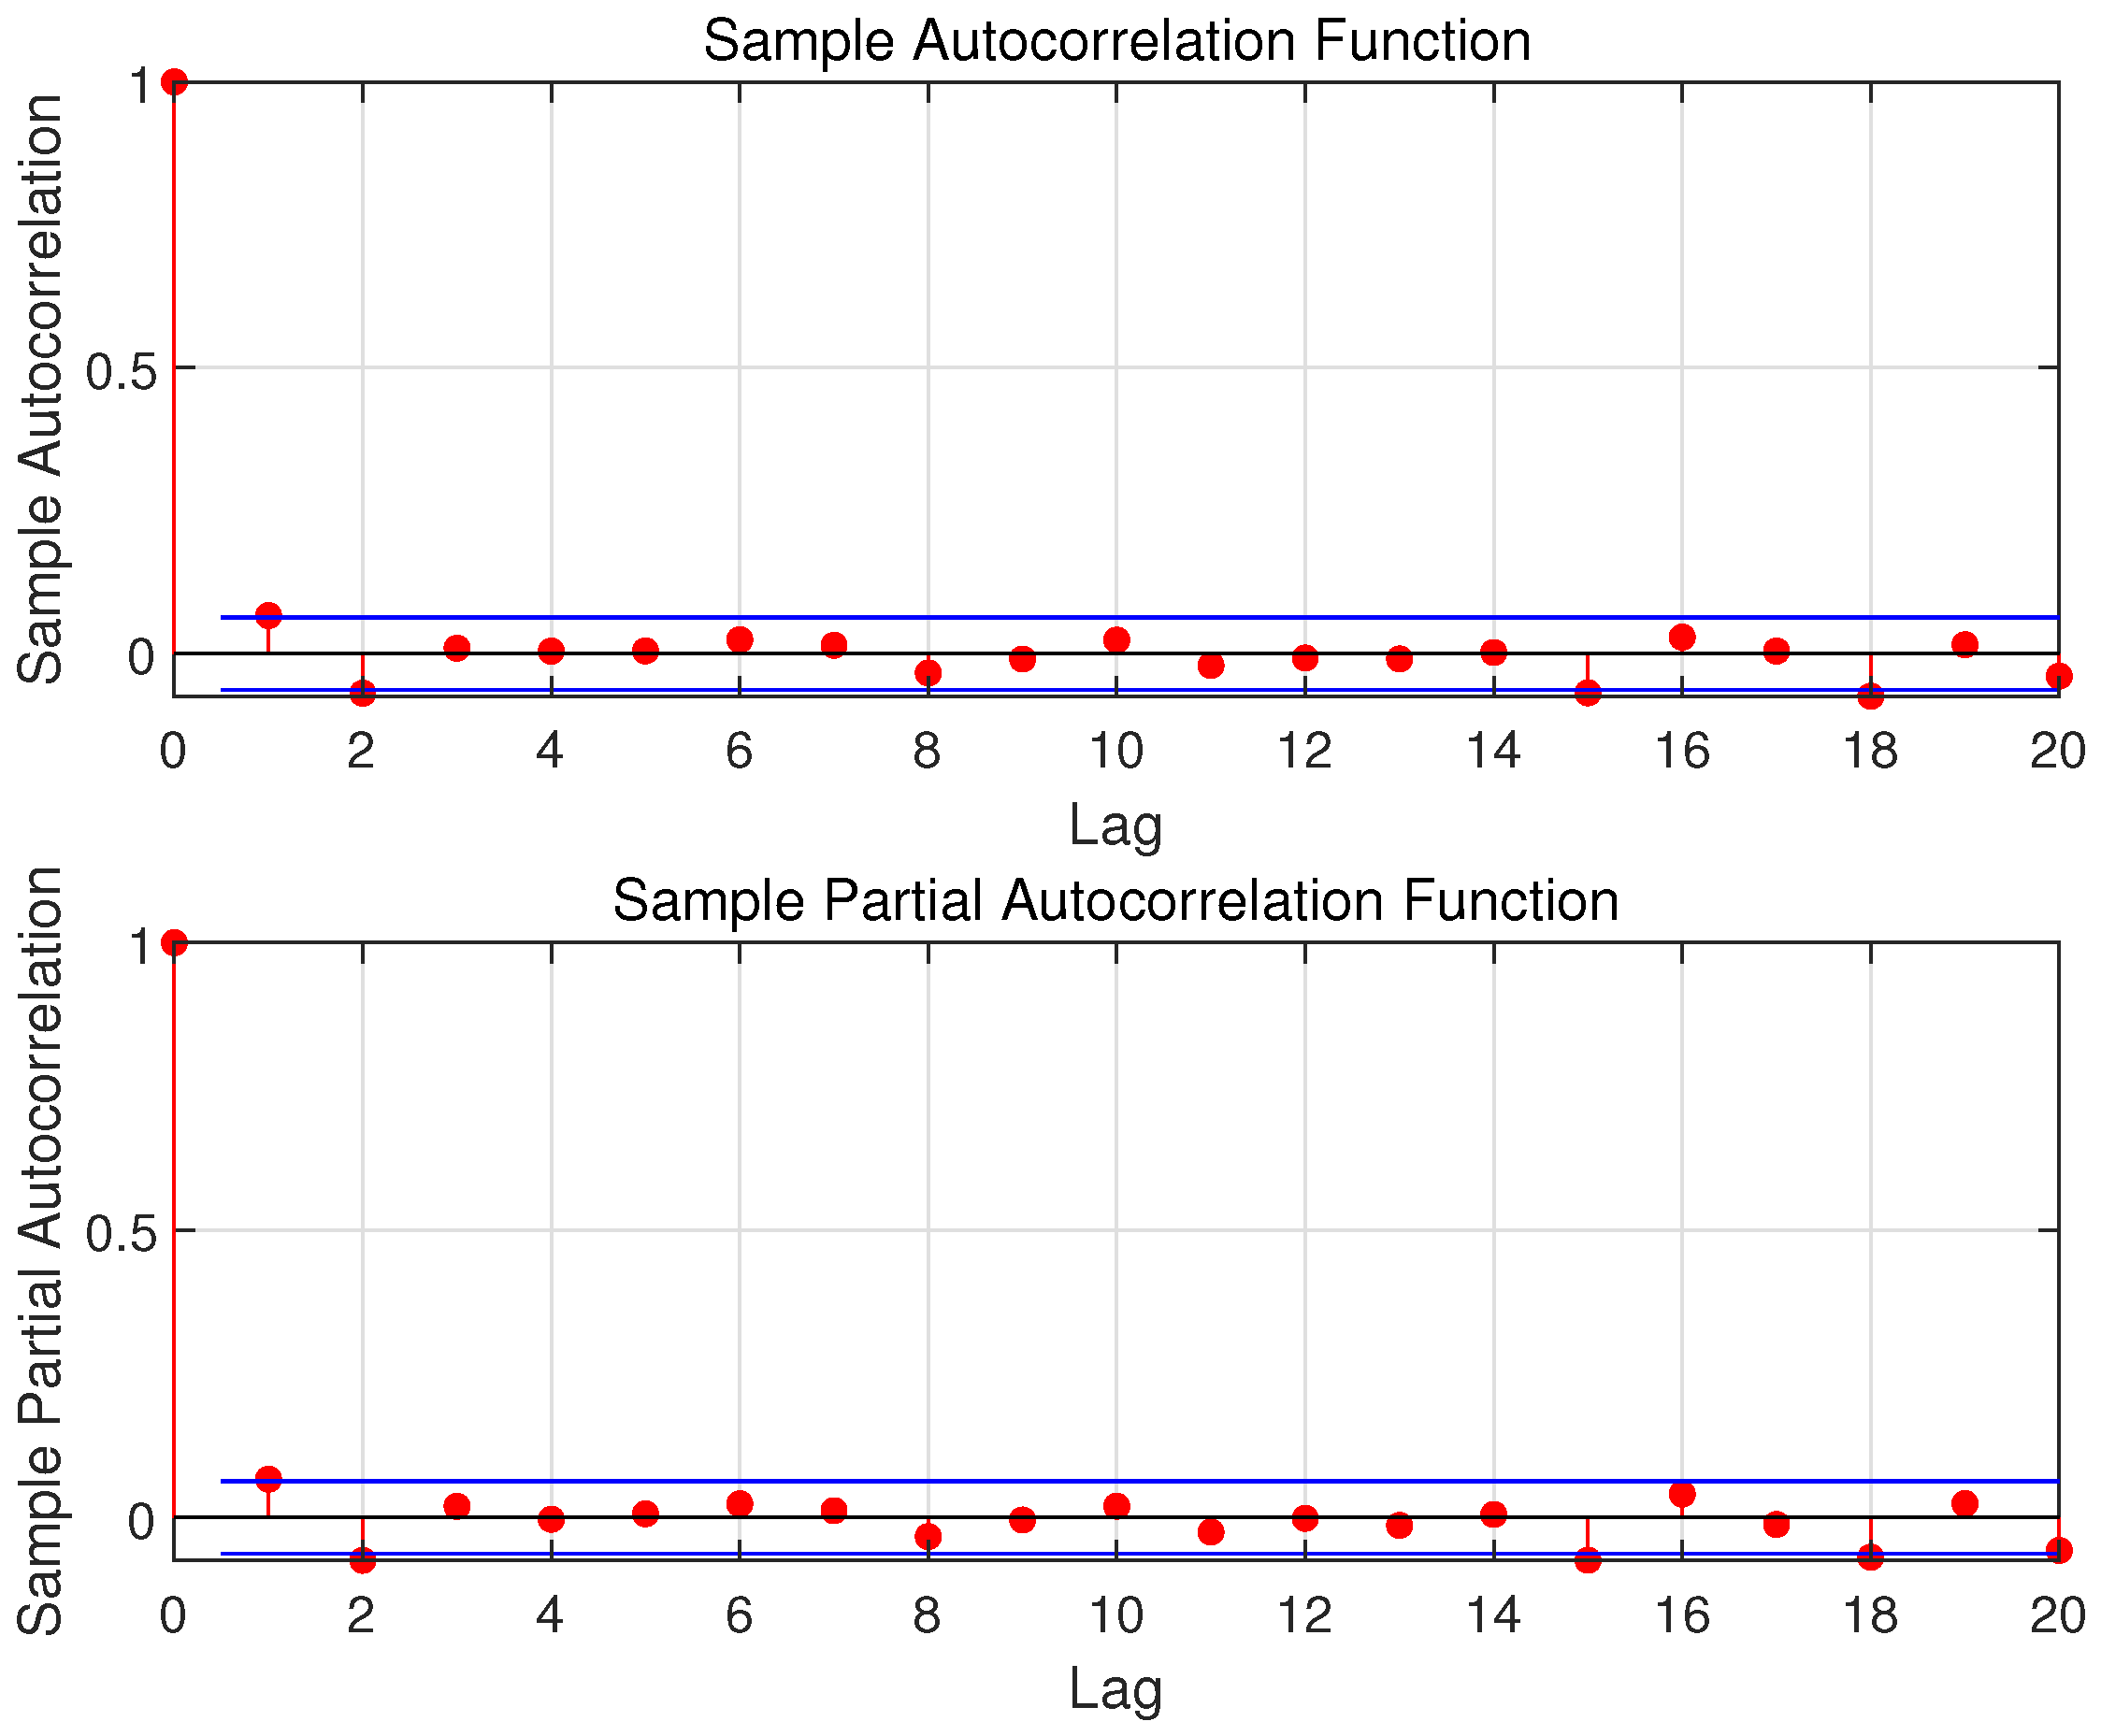
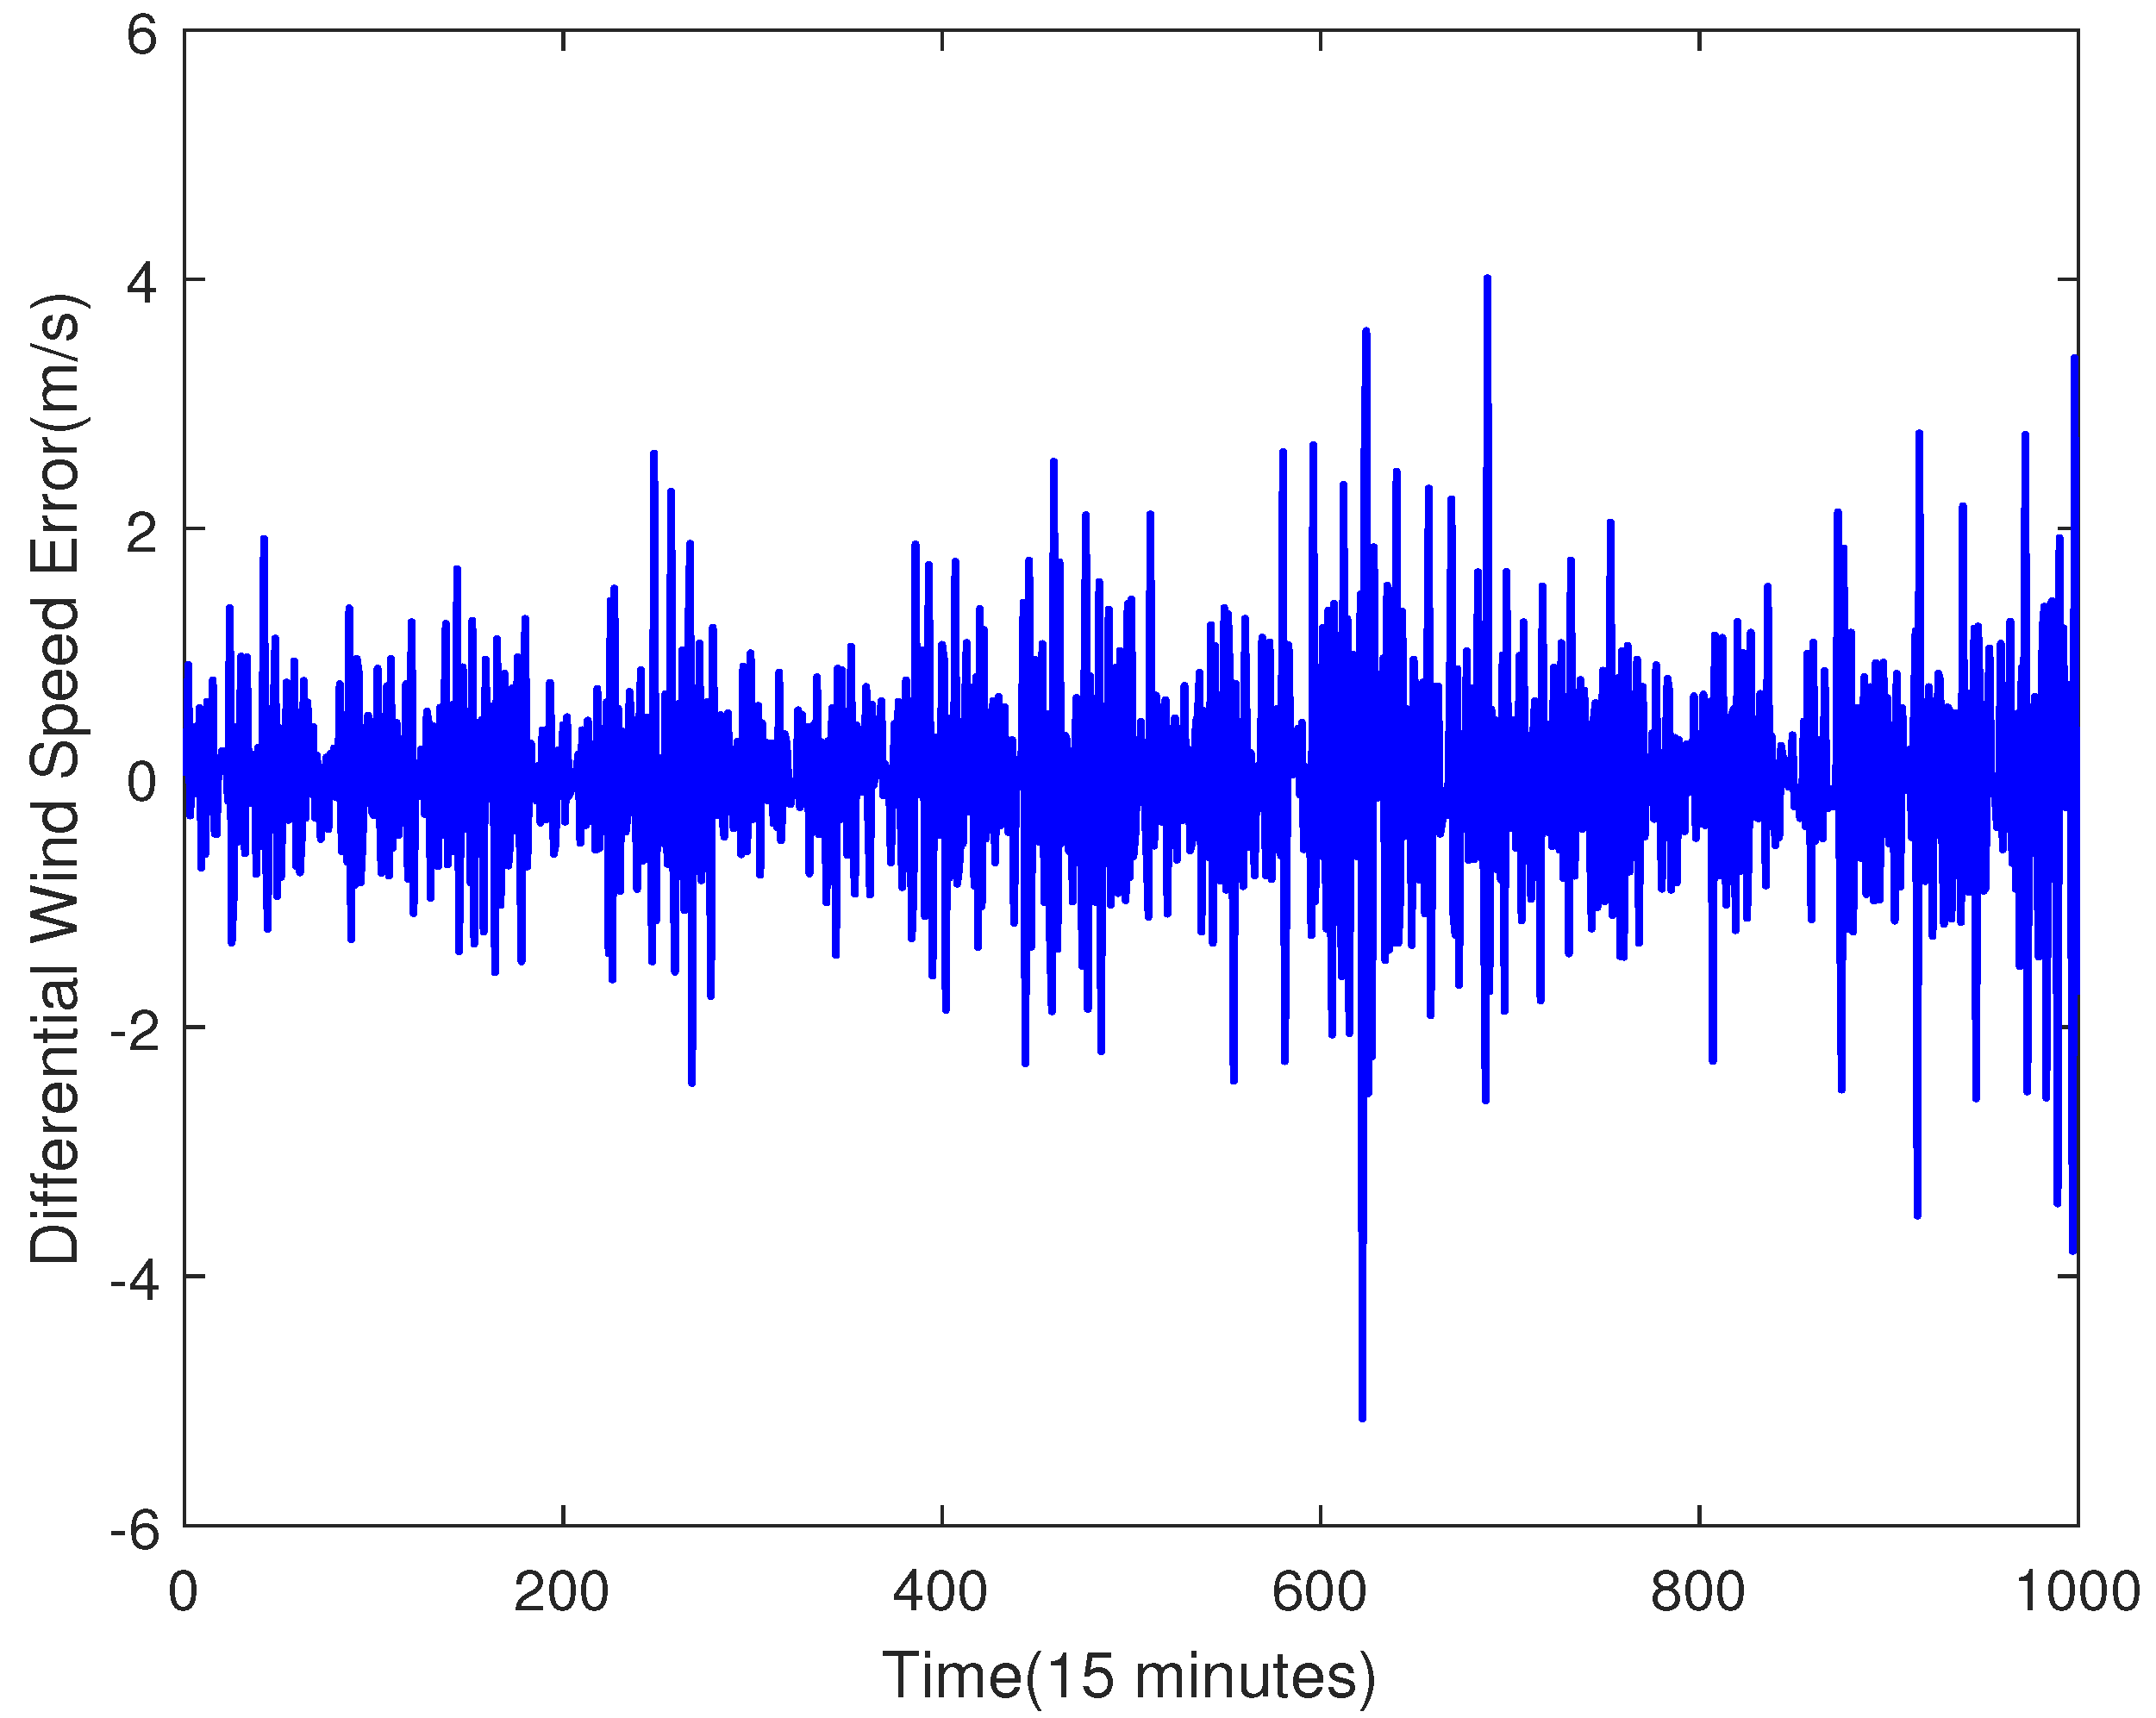
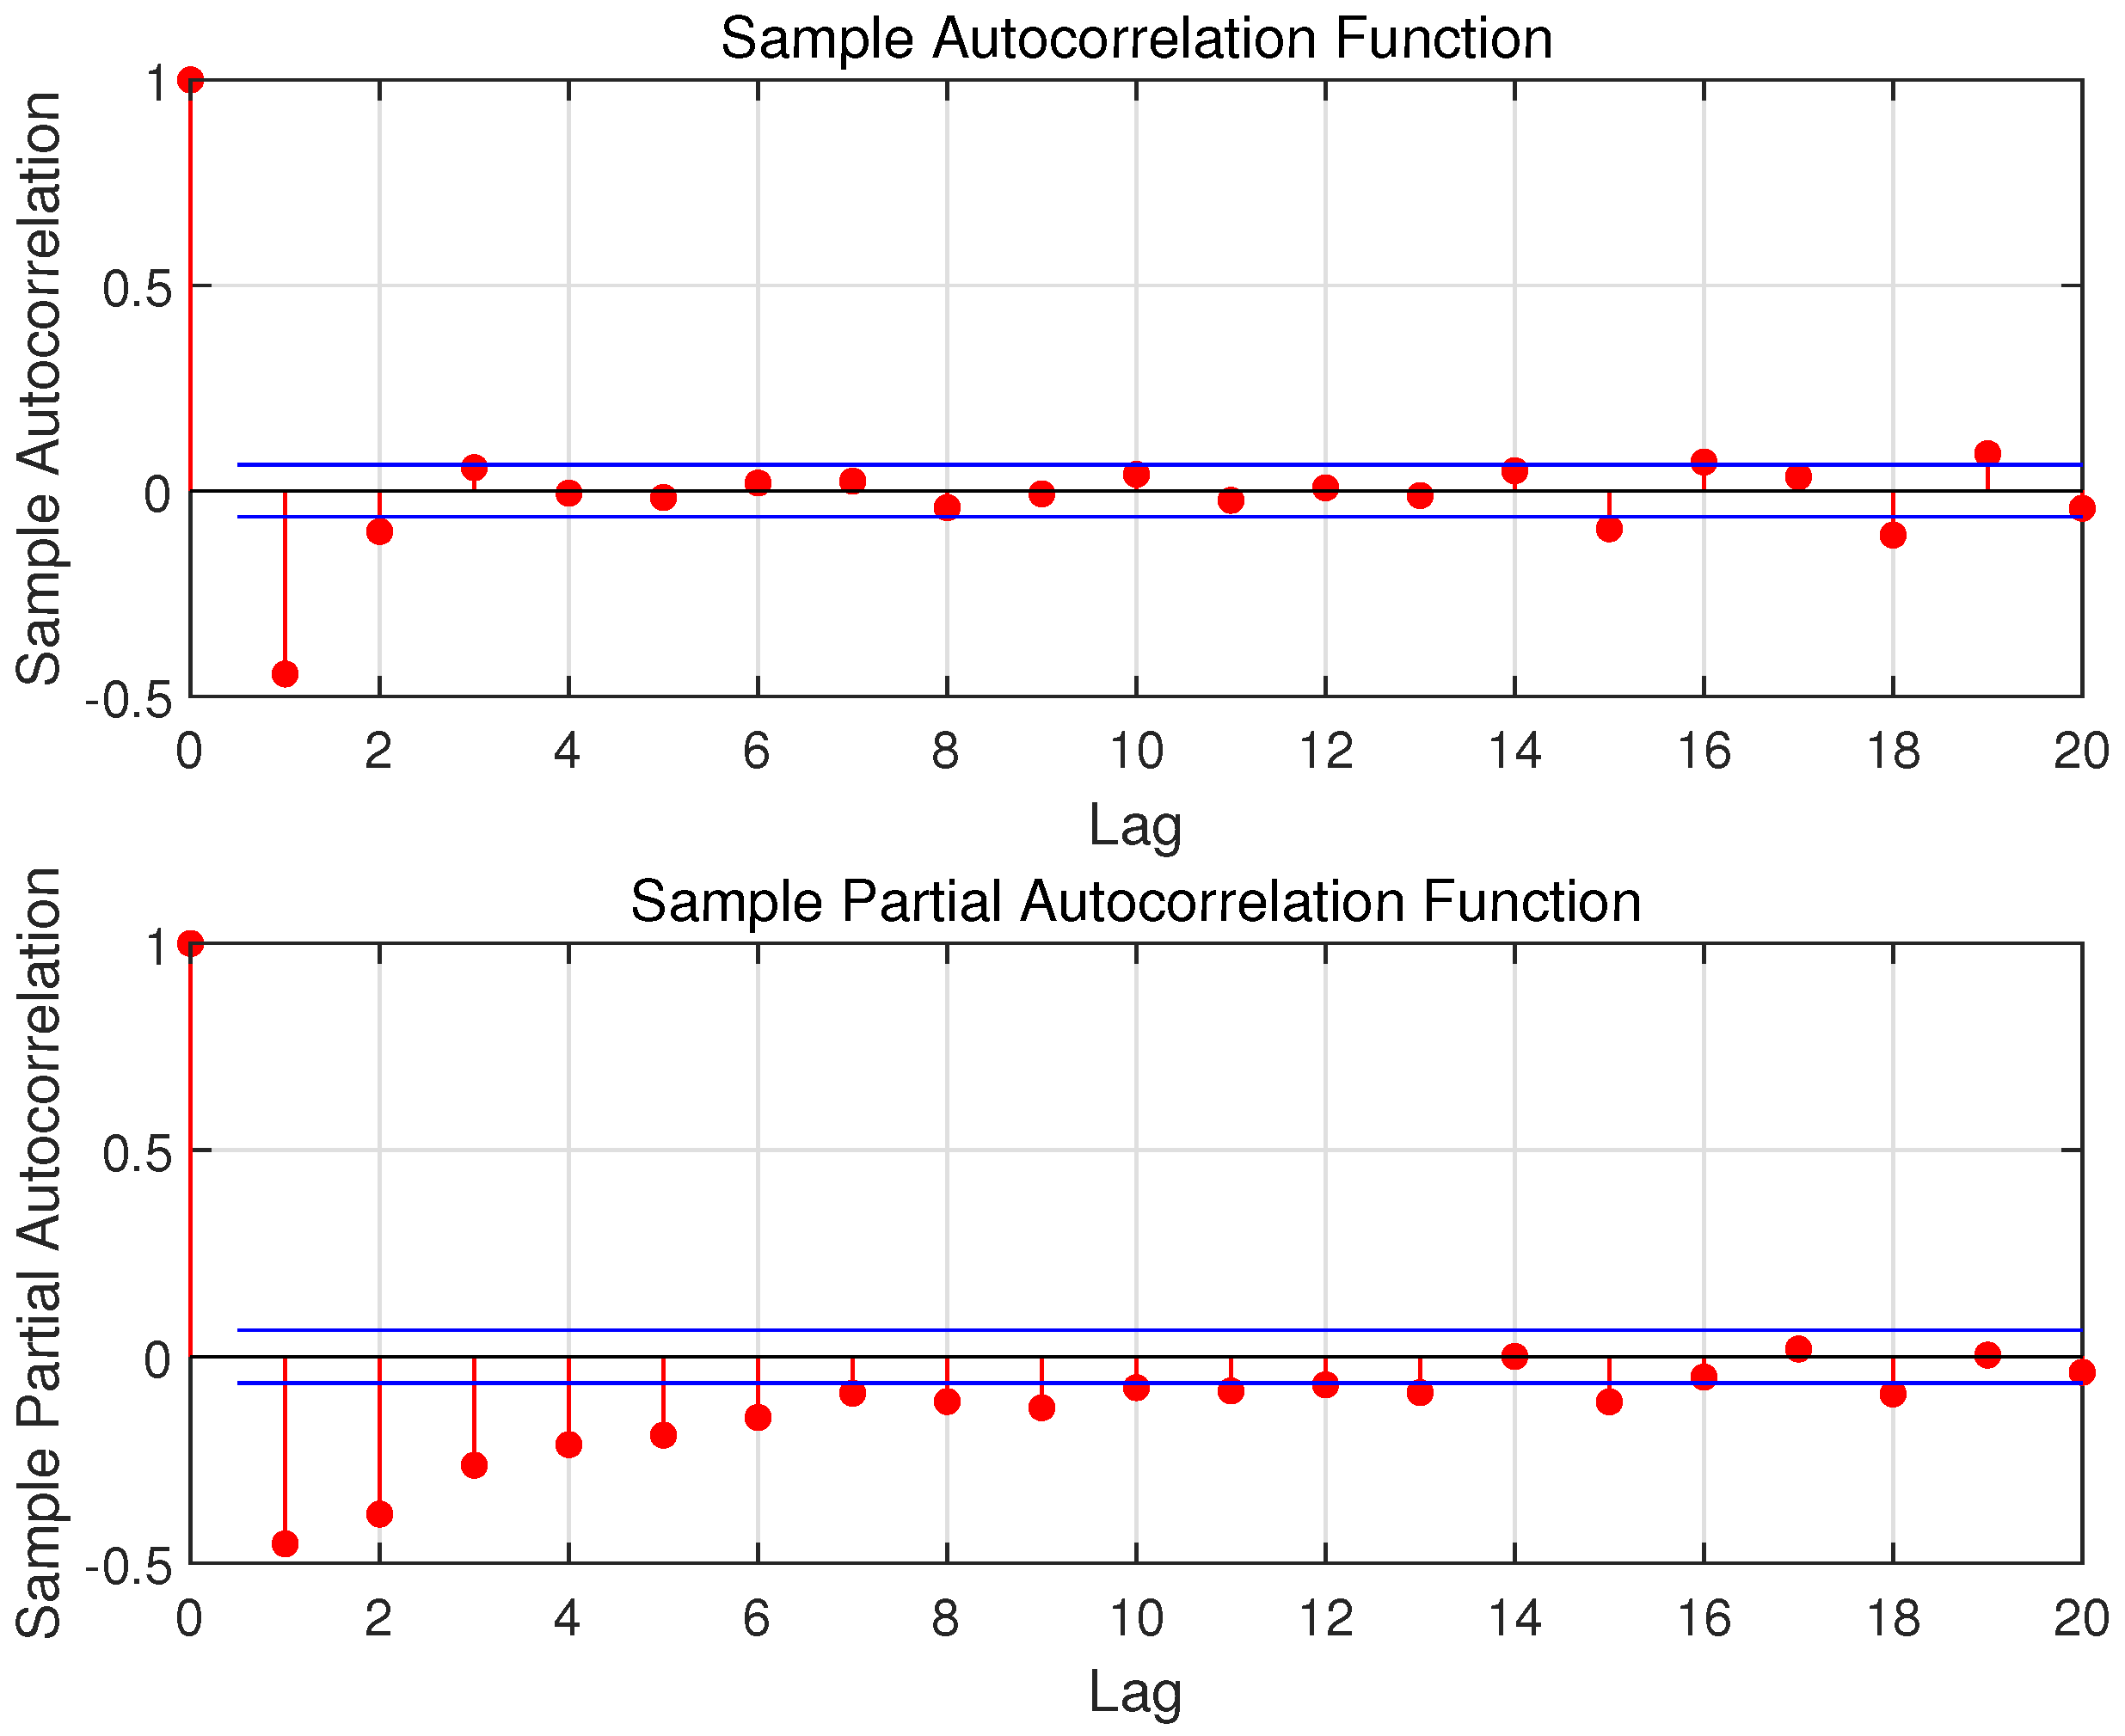
By using the ADF test operation, we prove that the raw data shown in Figure 2 are not a stable sequence. In order to make the sequence stable, this paper uses differential processing. It is worth noting that the testing set is considered unknown, and therefore, the training set is used to do the differential processing. The processing result is shown in Figure 3, and its ACF and PACF are shown in Figure 4. In this paper, the raw data after using the differential operation are used to obtain the ARMA model.
Figure 3.
The Raw Data After Difference.
Figure 4.
The ACF and PACF of Raw Data (The blue lines are the upper and lower confidence bounds).
The differential wind speed is shown in Figure 3. The ADF test is also used in this case, and the result also proves that the differential wind speed is a stationary sequence. Thus, it can be used for ARMA modelling.
4.1.2. ARMA Modeling
This step uses the differential data to establish the ARMA (p, q) model. The selection of p and q is an important step in the ARMA model. Figure 4 shows the ACF and PACF of the original data. Note that as ACF and PACF decrease, the relationship between historical wind speed and the future one becomes weaker and weaker. To guarantee the balance between the computation cost and the sufficiency of input features, the value range of p and q are respectively chosen as 3 to 7 and 4 to 7 [30]. Then, the AIC is used to find the relatively appropriate p and q in the ARMA (p, q) model. The specific method is to set a cycle and use the iterative method for each combination of p and q. The relatively appropriate values of p and q can be obtained when the AIC value is the minimum.
As shown in Table 1, the minimum AIC value is obtained when and . This means that the optimal value in data portioning should be 4.
Table 1.
The AIC Values of ARMA Model.
4.1.3. Data Partitioning
The optimal p is used to partition data. Every four data are divided into a group. The first three data are regarded as inputs, and the fourth data point is regarded as a target. The same processing is employed to all the wind speed data until all of them are portioned. This process is described by the following equation
4.1.4. Wind Speed Prediction
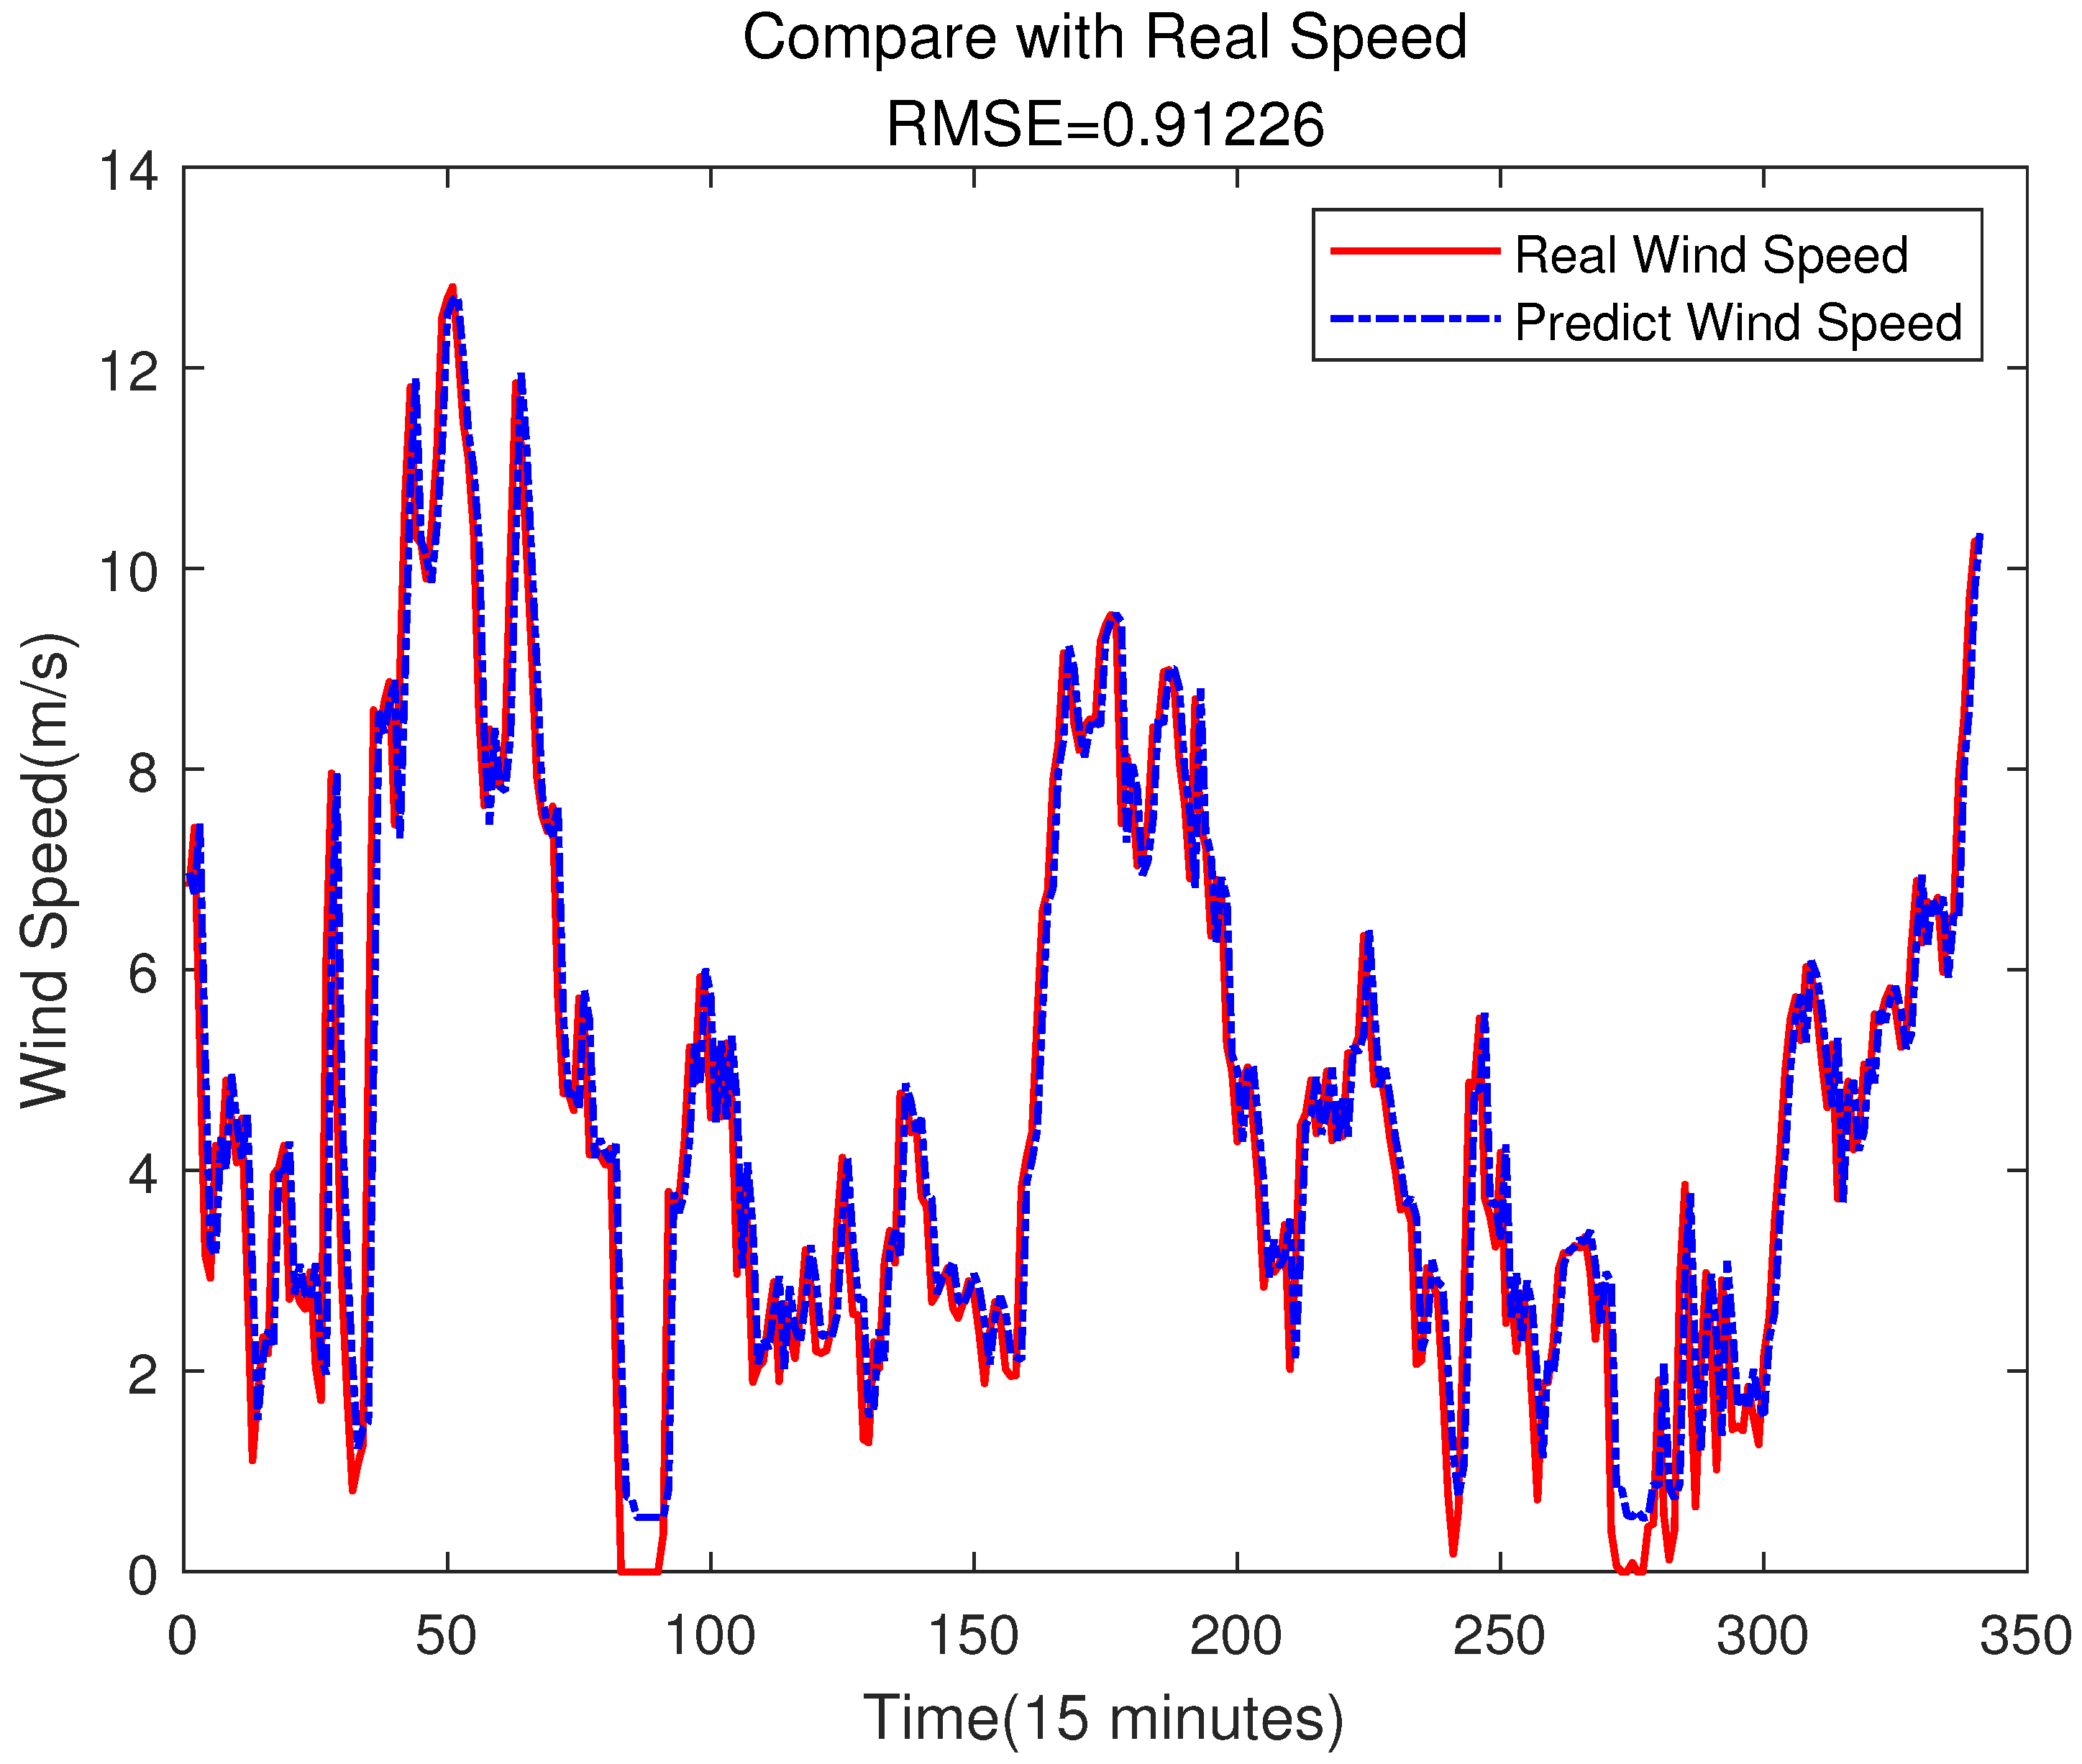
The SVR model can be trained by the partitioned data in Section 4.1.3, and then we can use the trained model to predict the wind speed. In this experiment, the choice of kernel function of the SVR model is RBF. The parameter of RBF is 0.0039, and the value of the penalty factor C is 6.285409. Both of them are selected by the trial and error method. The predicting result is shown in Figure 5.
Figure 5.
Wind Speed Prediction of SVR.
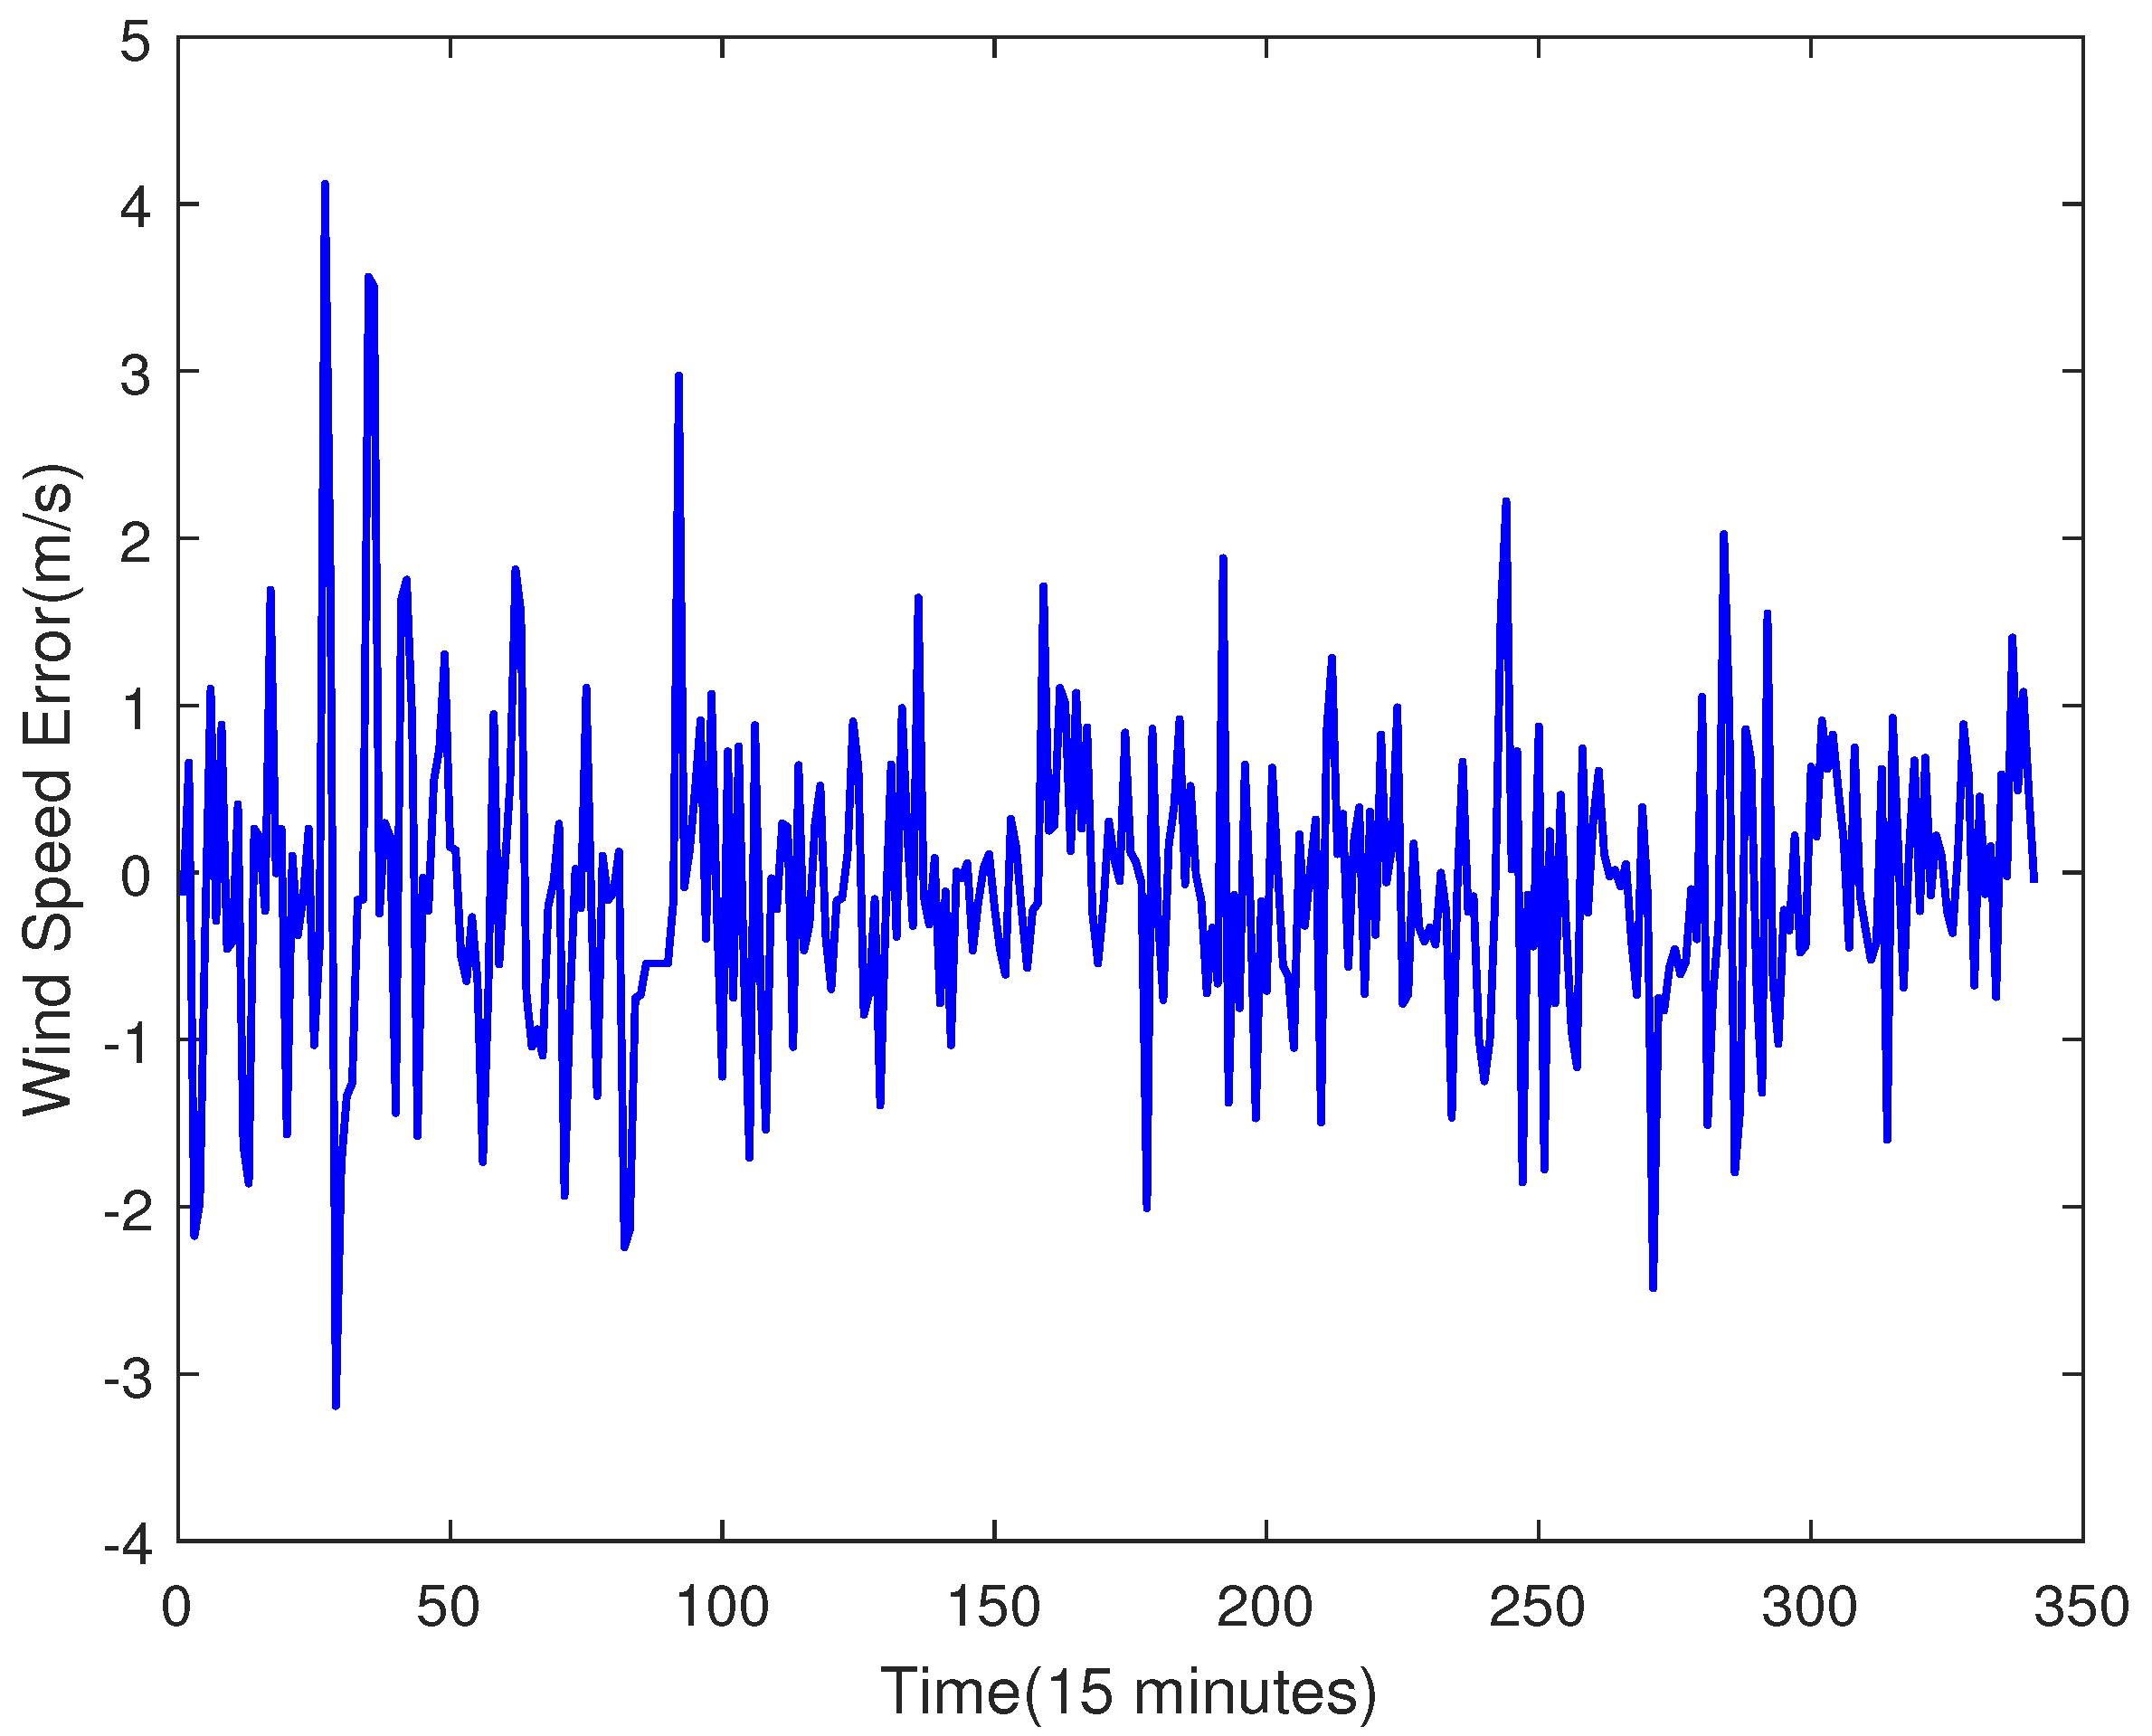
It can be seen from Figure 5 that the SVR model can effectively predict the change in wind speed on the whole. The prediction error is shown in Figure 6.
Figure 6.
The Prediction Error.
4.2. Experiment Steps of Error Prediction
In order to further improve the prediction accuracy, an error compensation prediction based on ELM is used in this paper. In this method, the ELM is used to predict the error. Then, a more accurate wind speed prediction result can be obtained by adding the the error prediction result and the wind speed prediction result.
4.2.1. Error Data Processing and Modeling
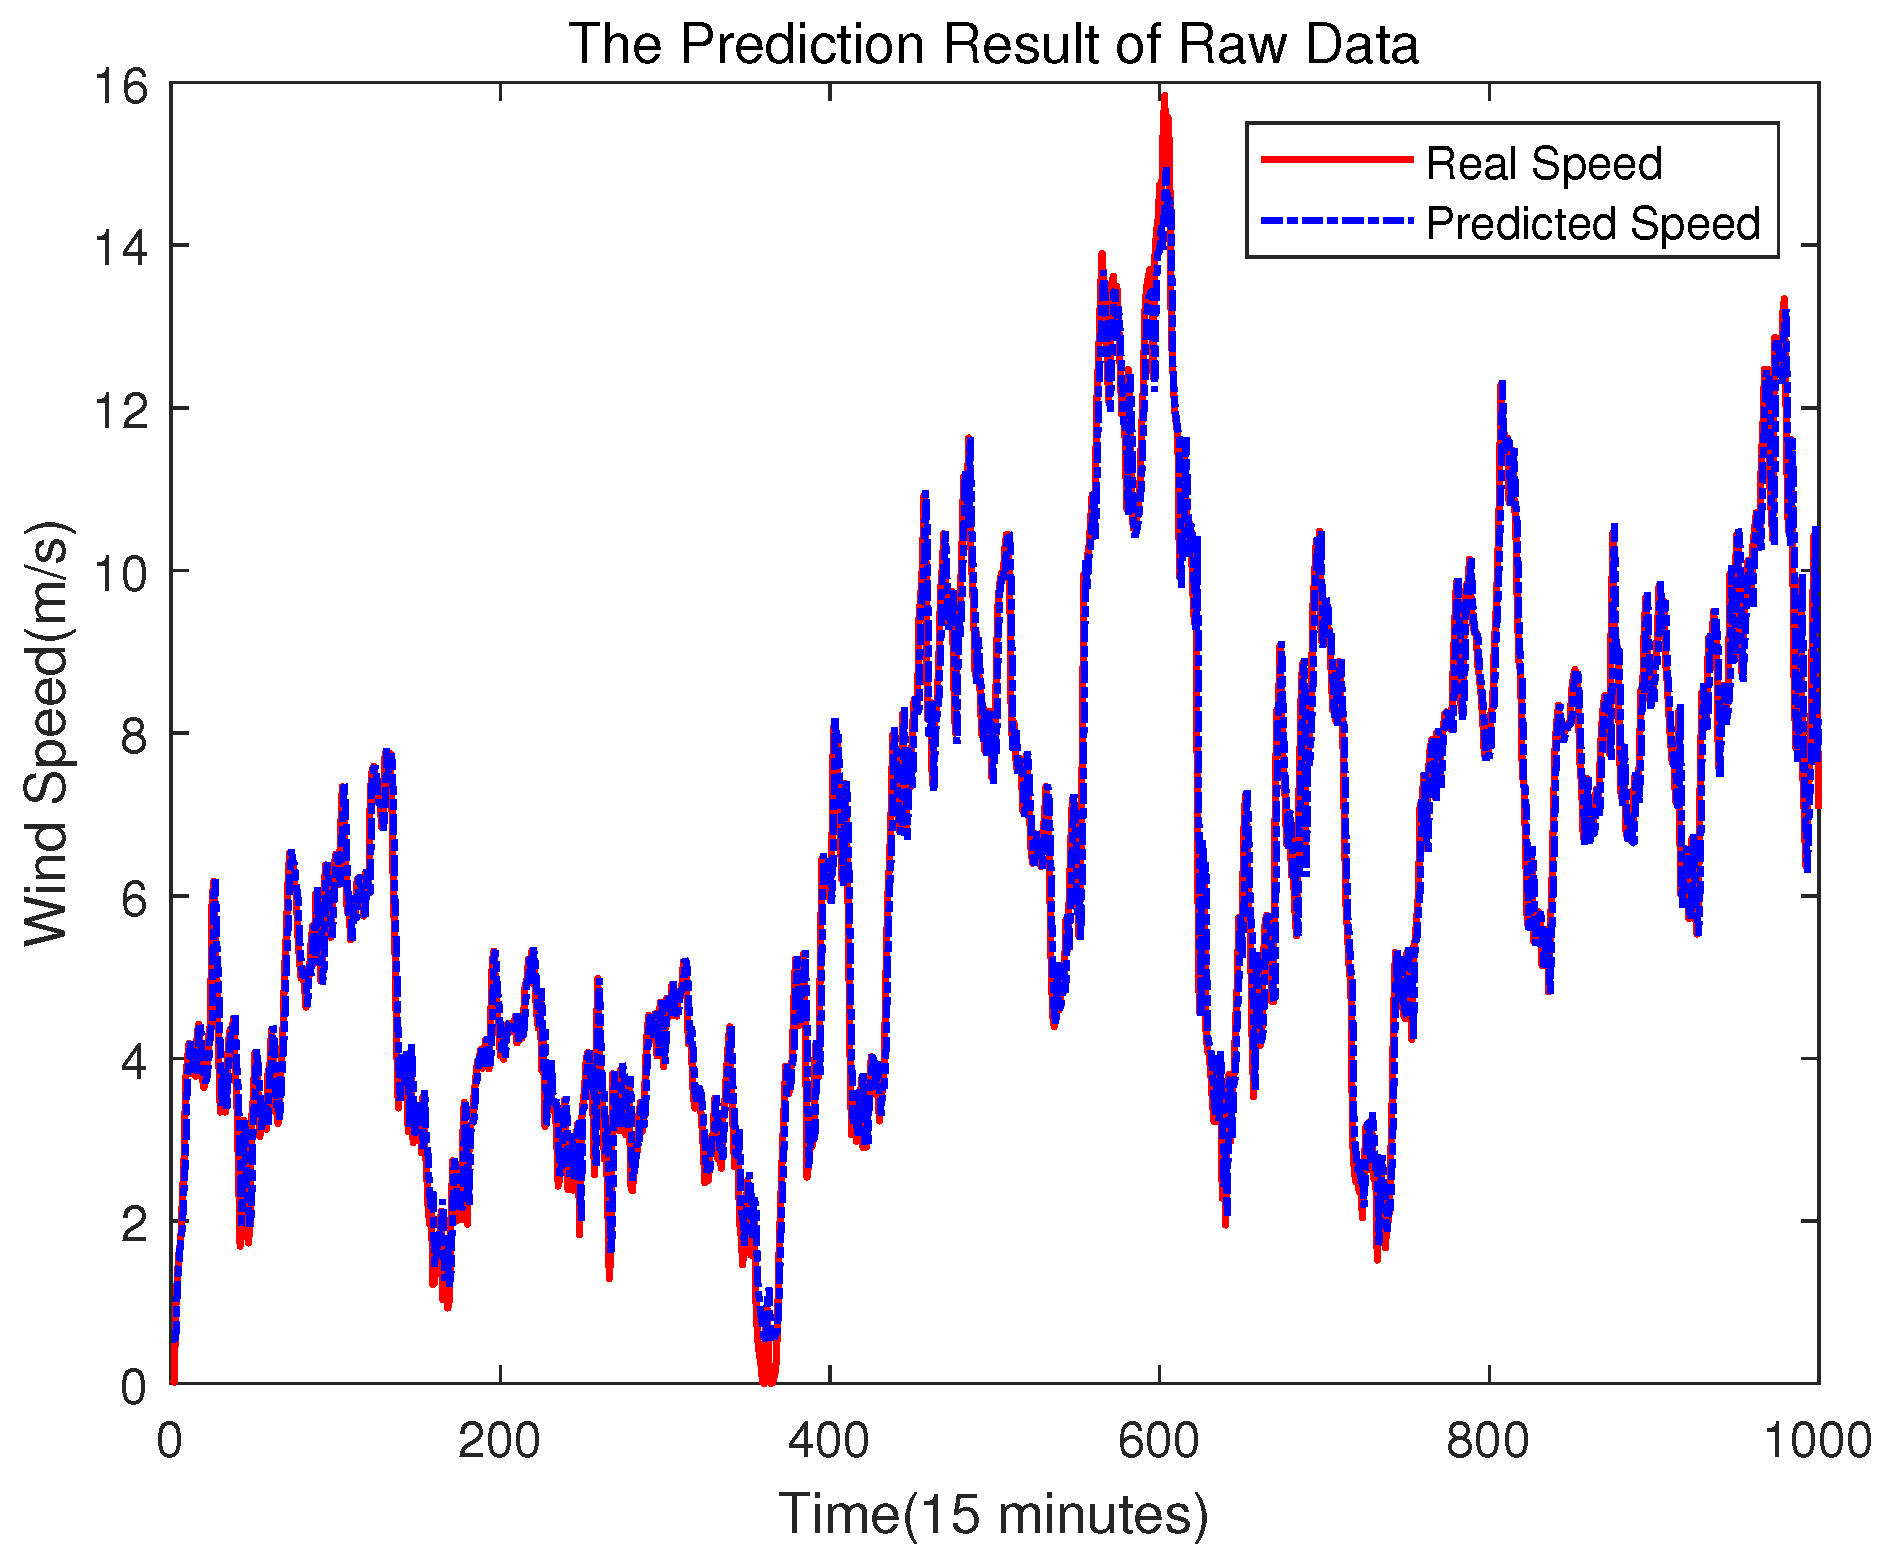
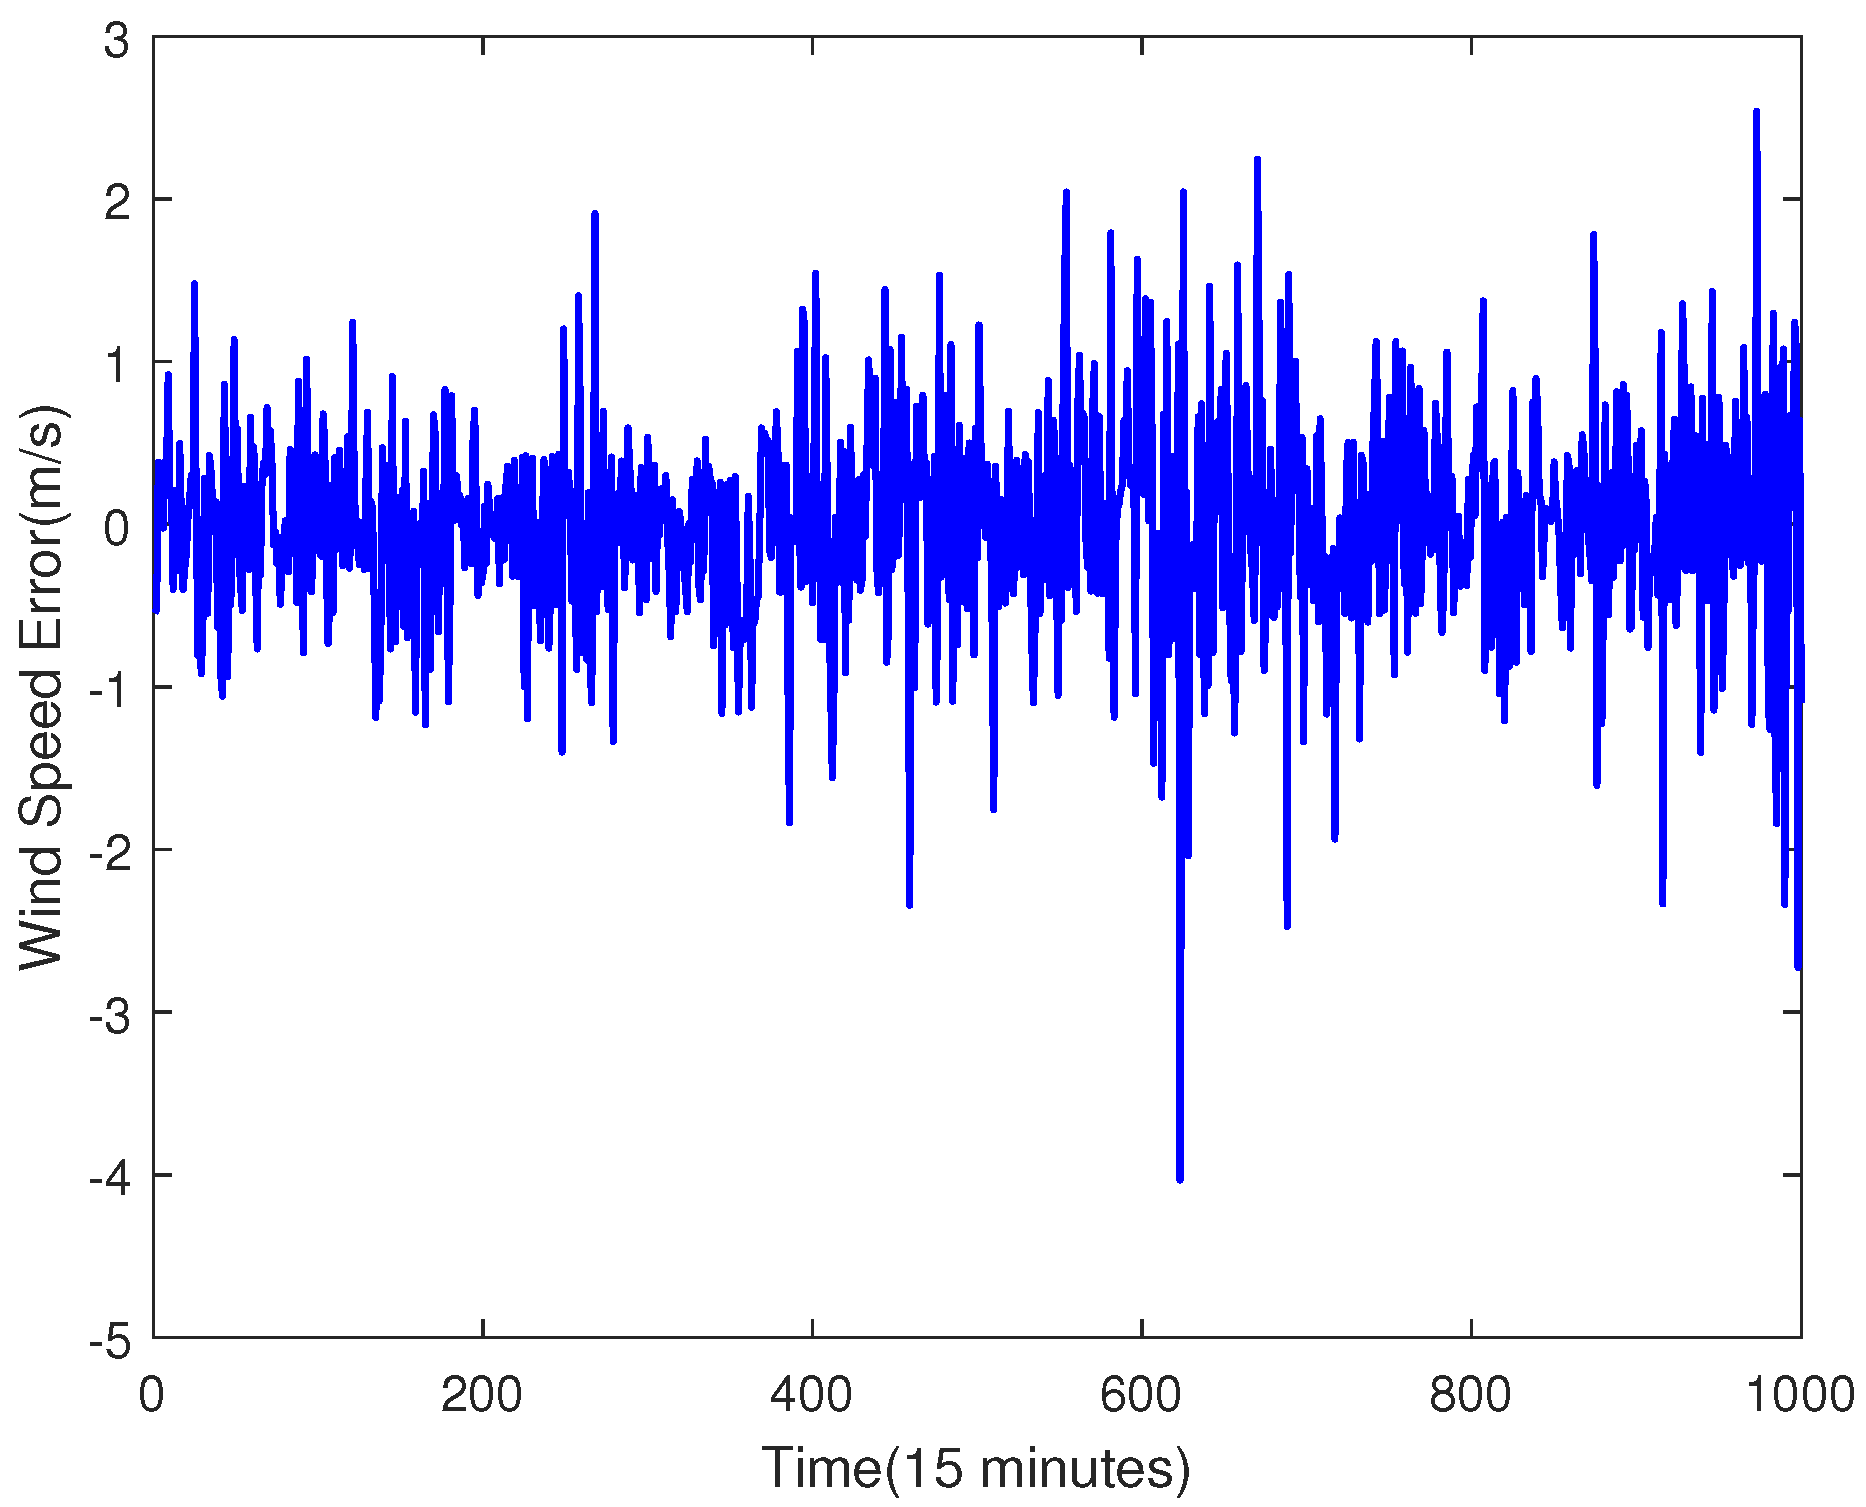
The trained SVR model is used to predict the original data, which is shown in Figure 7. Then, the error sequence can be obtained by subtracting the predicted value from the original data, which is shown in Figure 8.
Figure 7.
The Result of Raw Data Prediction.
Figure 8.
The Raw Error Data.
Like the original data, the error data are also a univariate time series. Therefore, the data processing method is the same as that of the original data.
As shown in Figure 8, the sequence looks stable, but it does not pass the ADF test. Therefore, the sequence needs to be differentiated. The differential result is shown in Figure 9, and the ACF and PACF are shown in Figure 10.
Figure 9.
The Differential Error Data.
Figure 10.
The ACF and PACF of Error Series (The blue lines are the upper and lower confidence bounds).
It can be estimated from Figure 10 that the optimal values of p and q in ARMA (p, q) should be both around 5 to 7. Therefore, the AIC criterion is used to find the most reasonable values of p and q. The result of AIC is shown in Table 2.
Table 2.
The AIC Values of Error ARMA Model.
As Table 2 shows, the minimum AIC value is obtained when , . Therefore, the theoretical optimal ARMA model is ARMA(5, 3).
4.2.2. Error Data Partitioning and Predicting
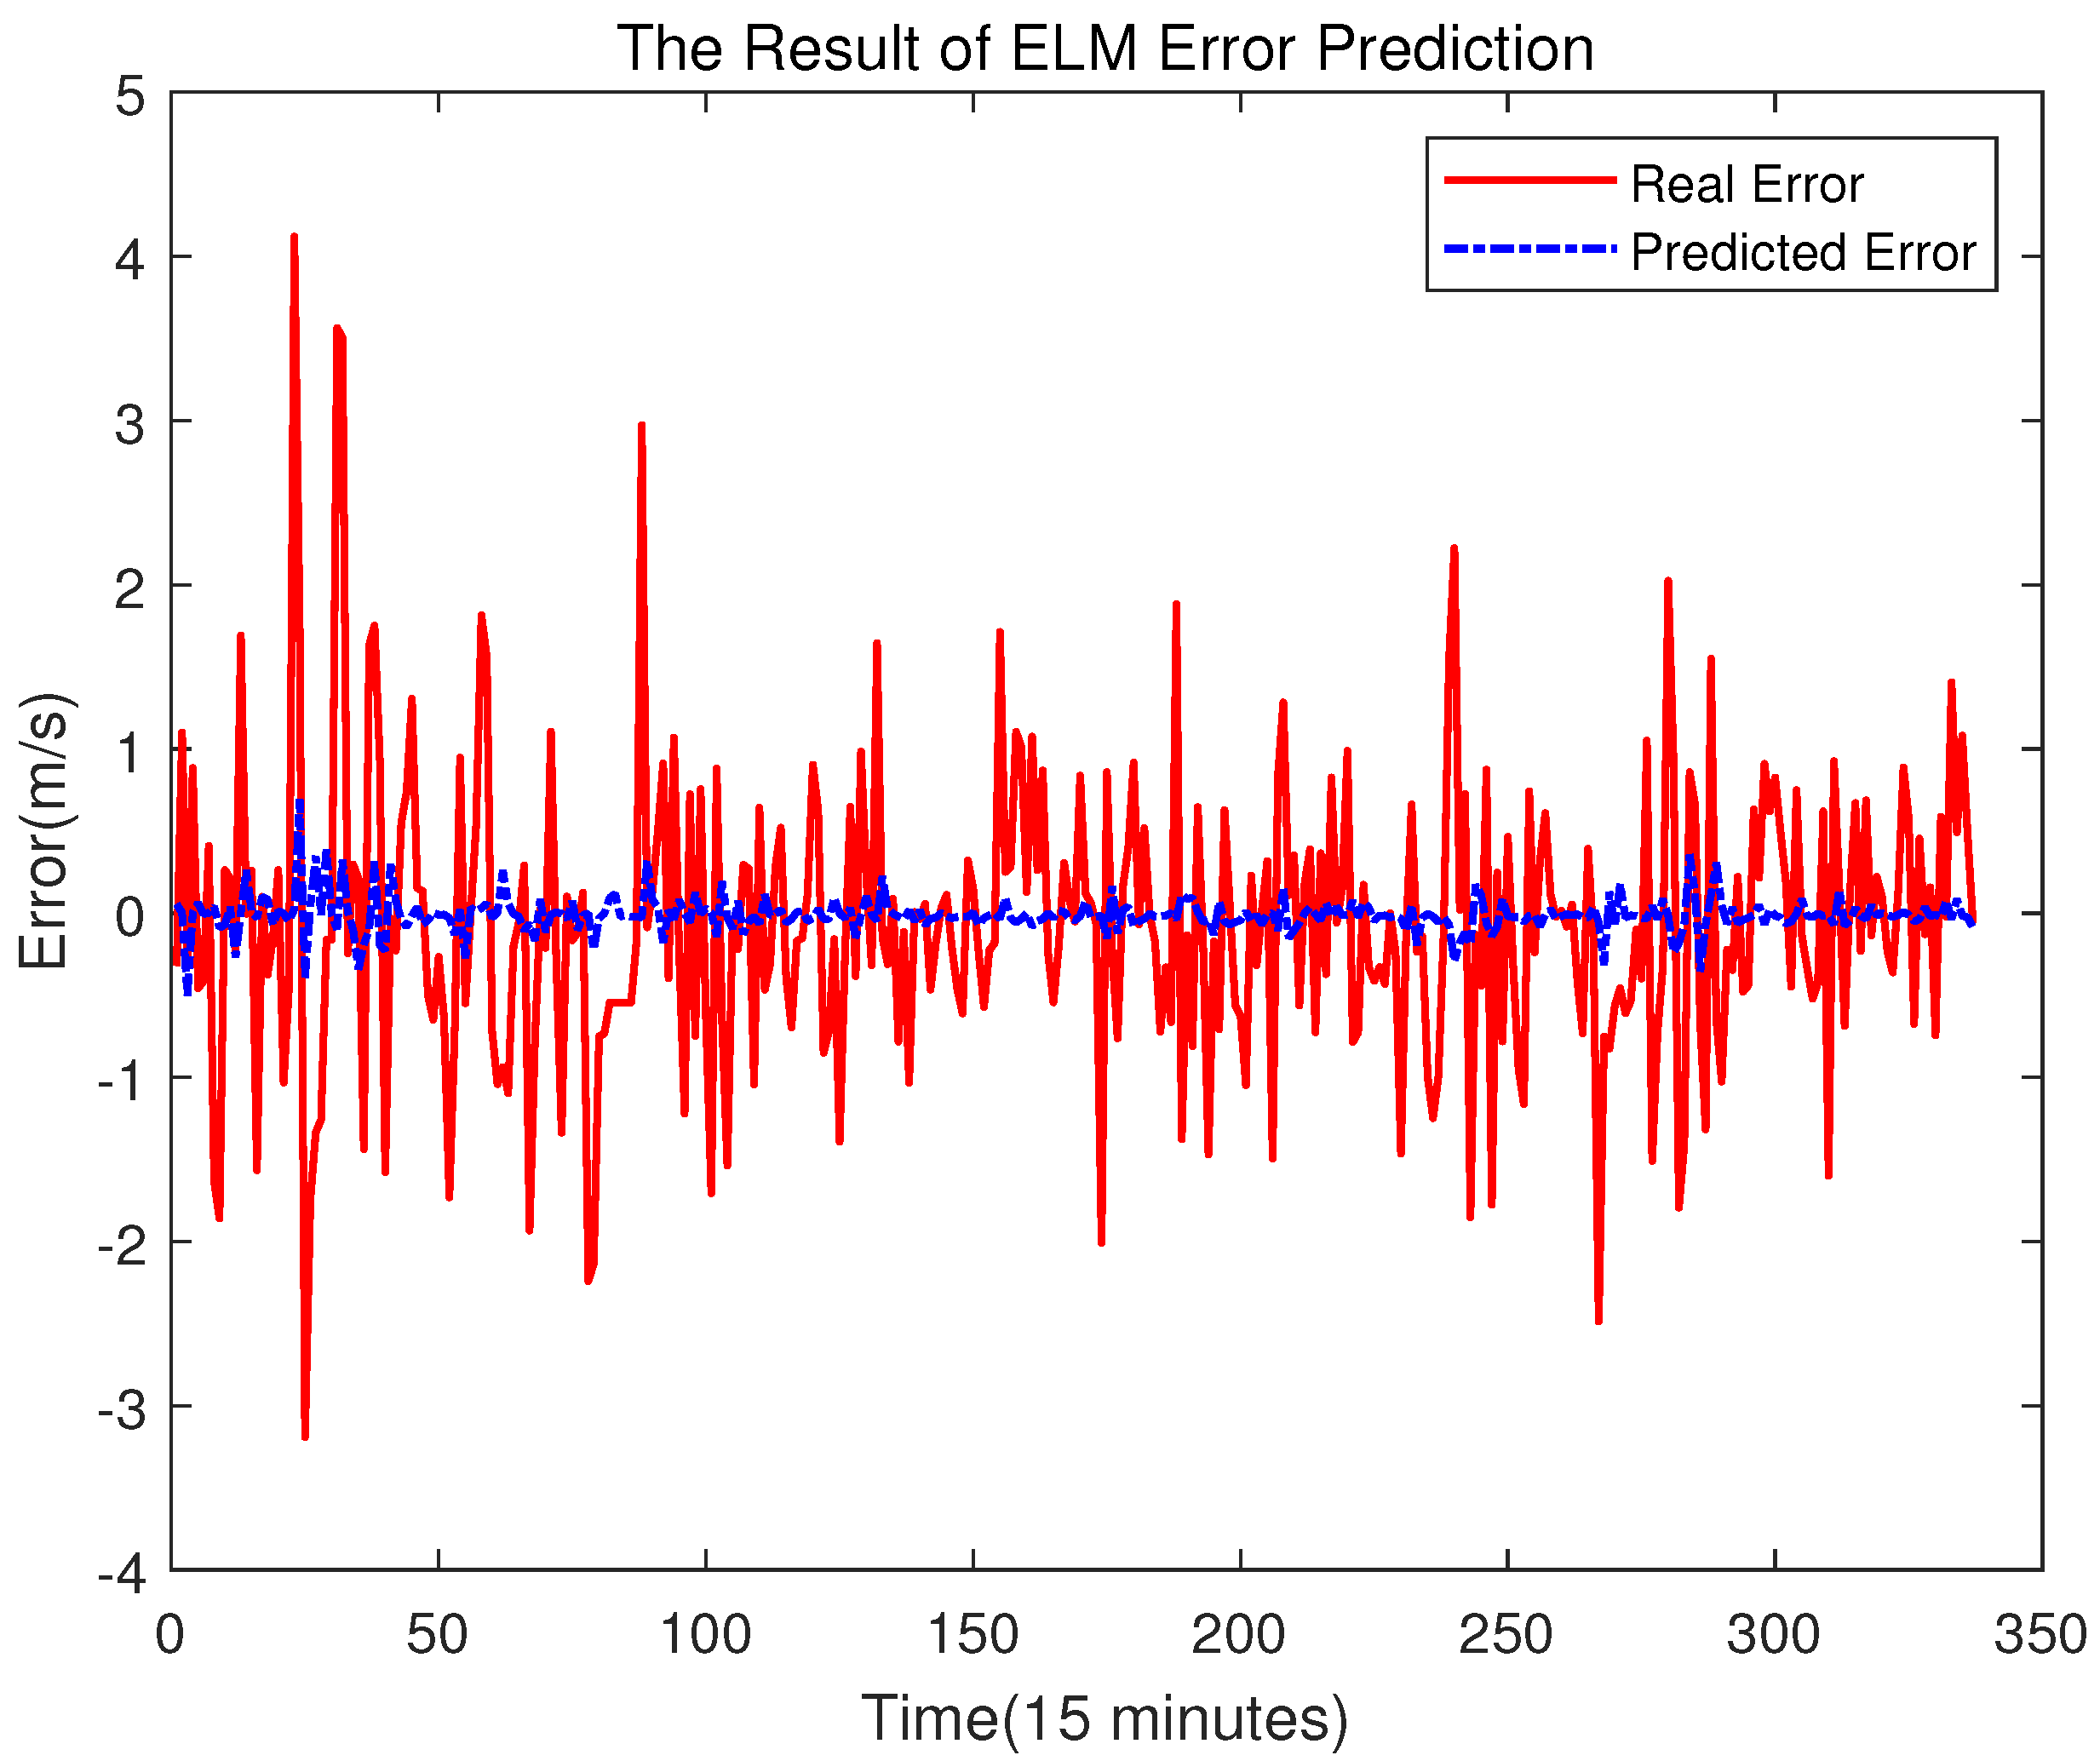
The method of dividing data is the same as before: the p value is used to divide the data into multiple groups. The first numbers of each group are regarded as the input, and the pth data is regarded as the target. Then, the partitioned data are used to train the ELM model to predict the future error. In this step, the activation function of the ELM model is the Sigmoid Function, and the number of hidden layer neurons is 10. The result of the error prediction is shown in Figure 11.
Figure 11.
Error Prediction of ELM.
From Figure 11, one may see that the deviations between the real error and the predicted one is relatively big. However, for error compensation, as long as the changing trend is predicted correctly, the accuracy of the final predicted result will also be improved. As shown in Figure 11, the changing trend of wind speed error is accurately predicted by using the proposed error correction technique. Thus, more accurate wind prediction results can be achieved after error compensation in our study.
4.2.3. Add Error Prediction and Wind Speed Prediction
After the results of wind speed prediction and error prediction are obtained, the final wind speed prediction result can be obtained by adding them up.
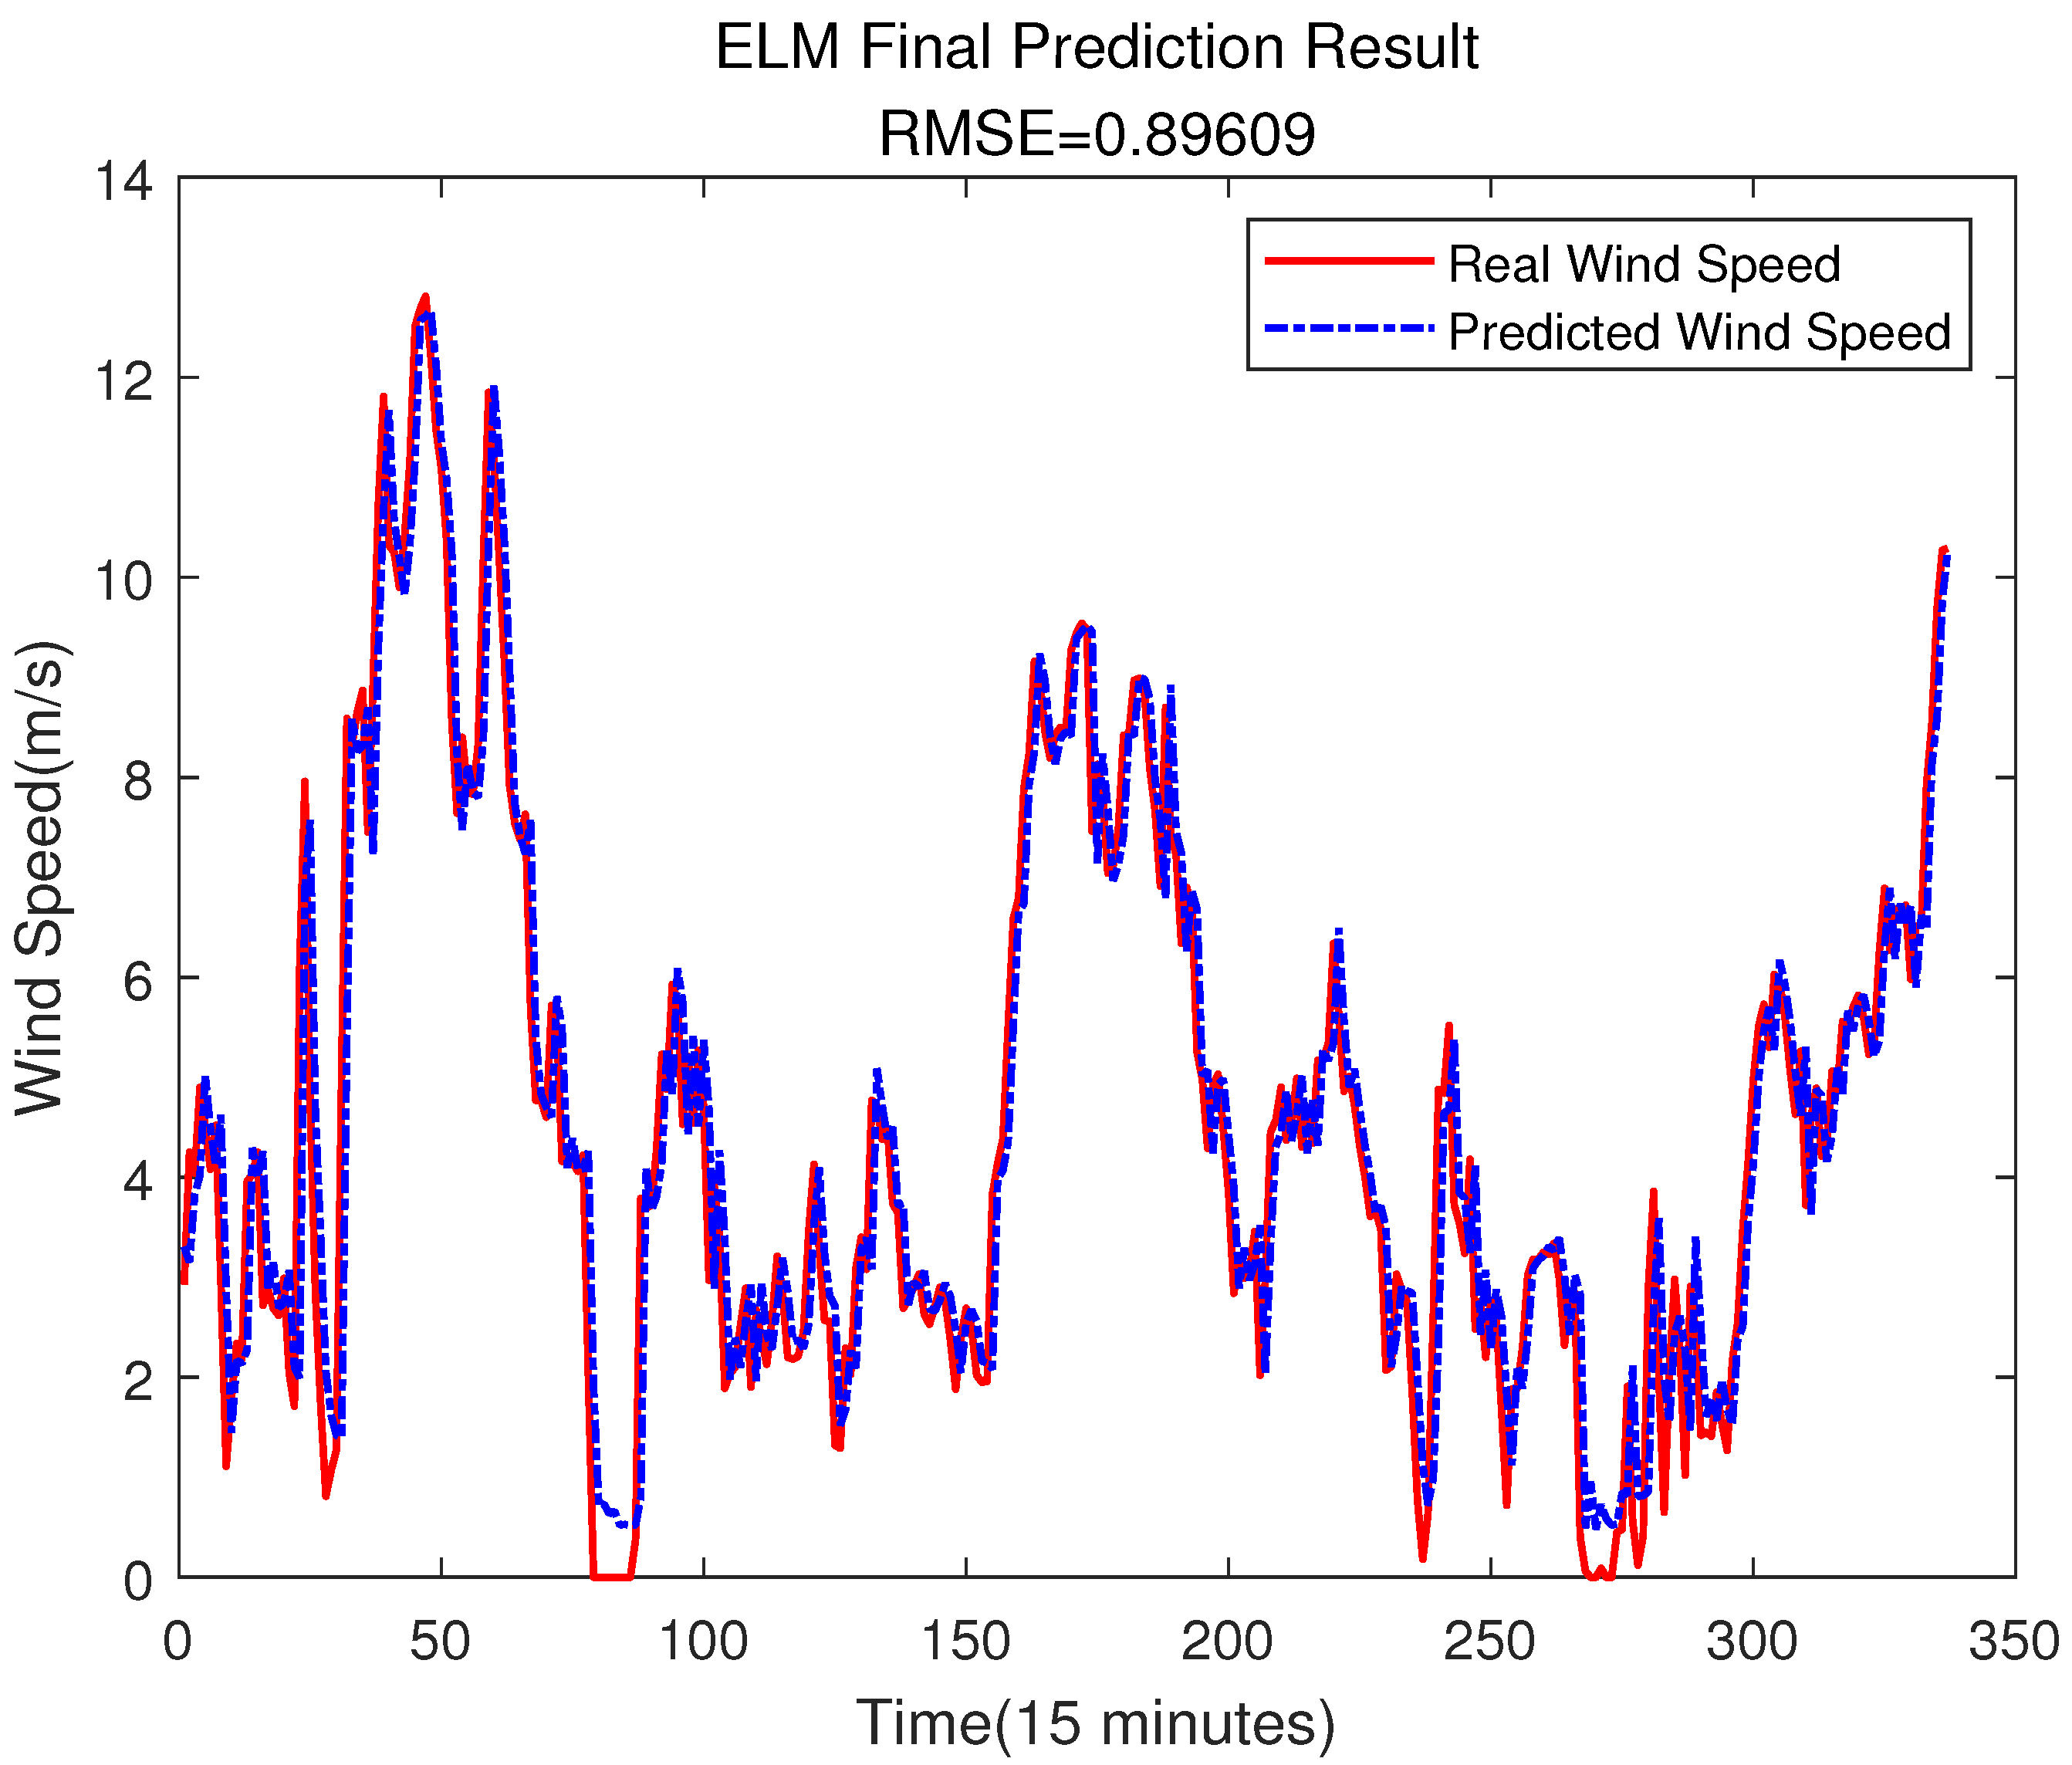
It is worth noting that due to the use of error compensation, the first few values in Figure 5 will be used as inputs to predict future values, which results in different images in Figure 5 and Figure 12 at the beginning, but this does not affect the experimental results.
Figure 12.
The Final Prediction Result.
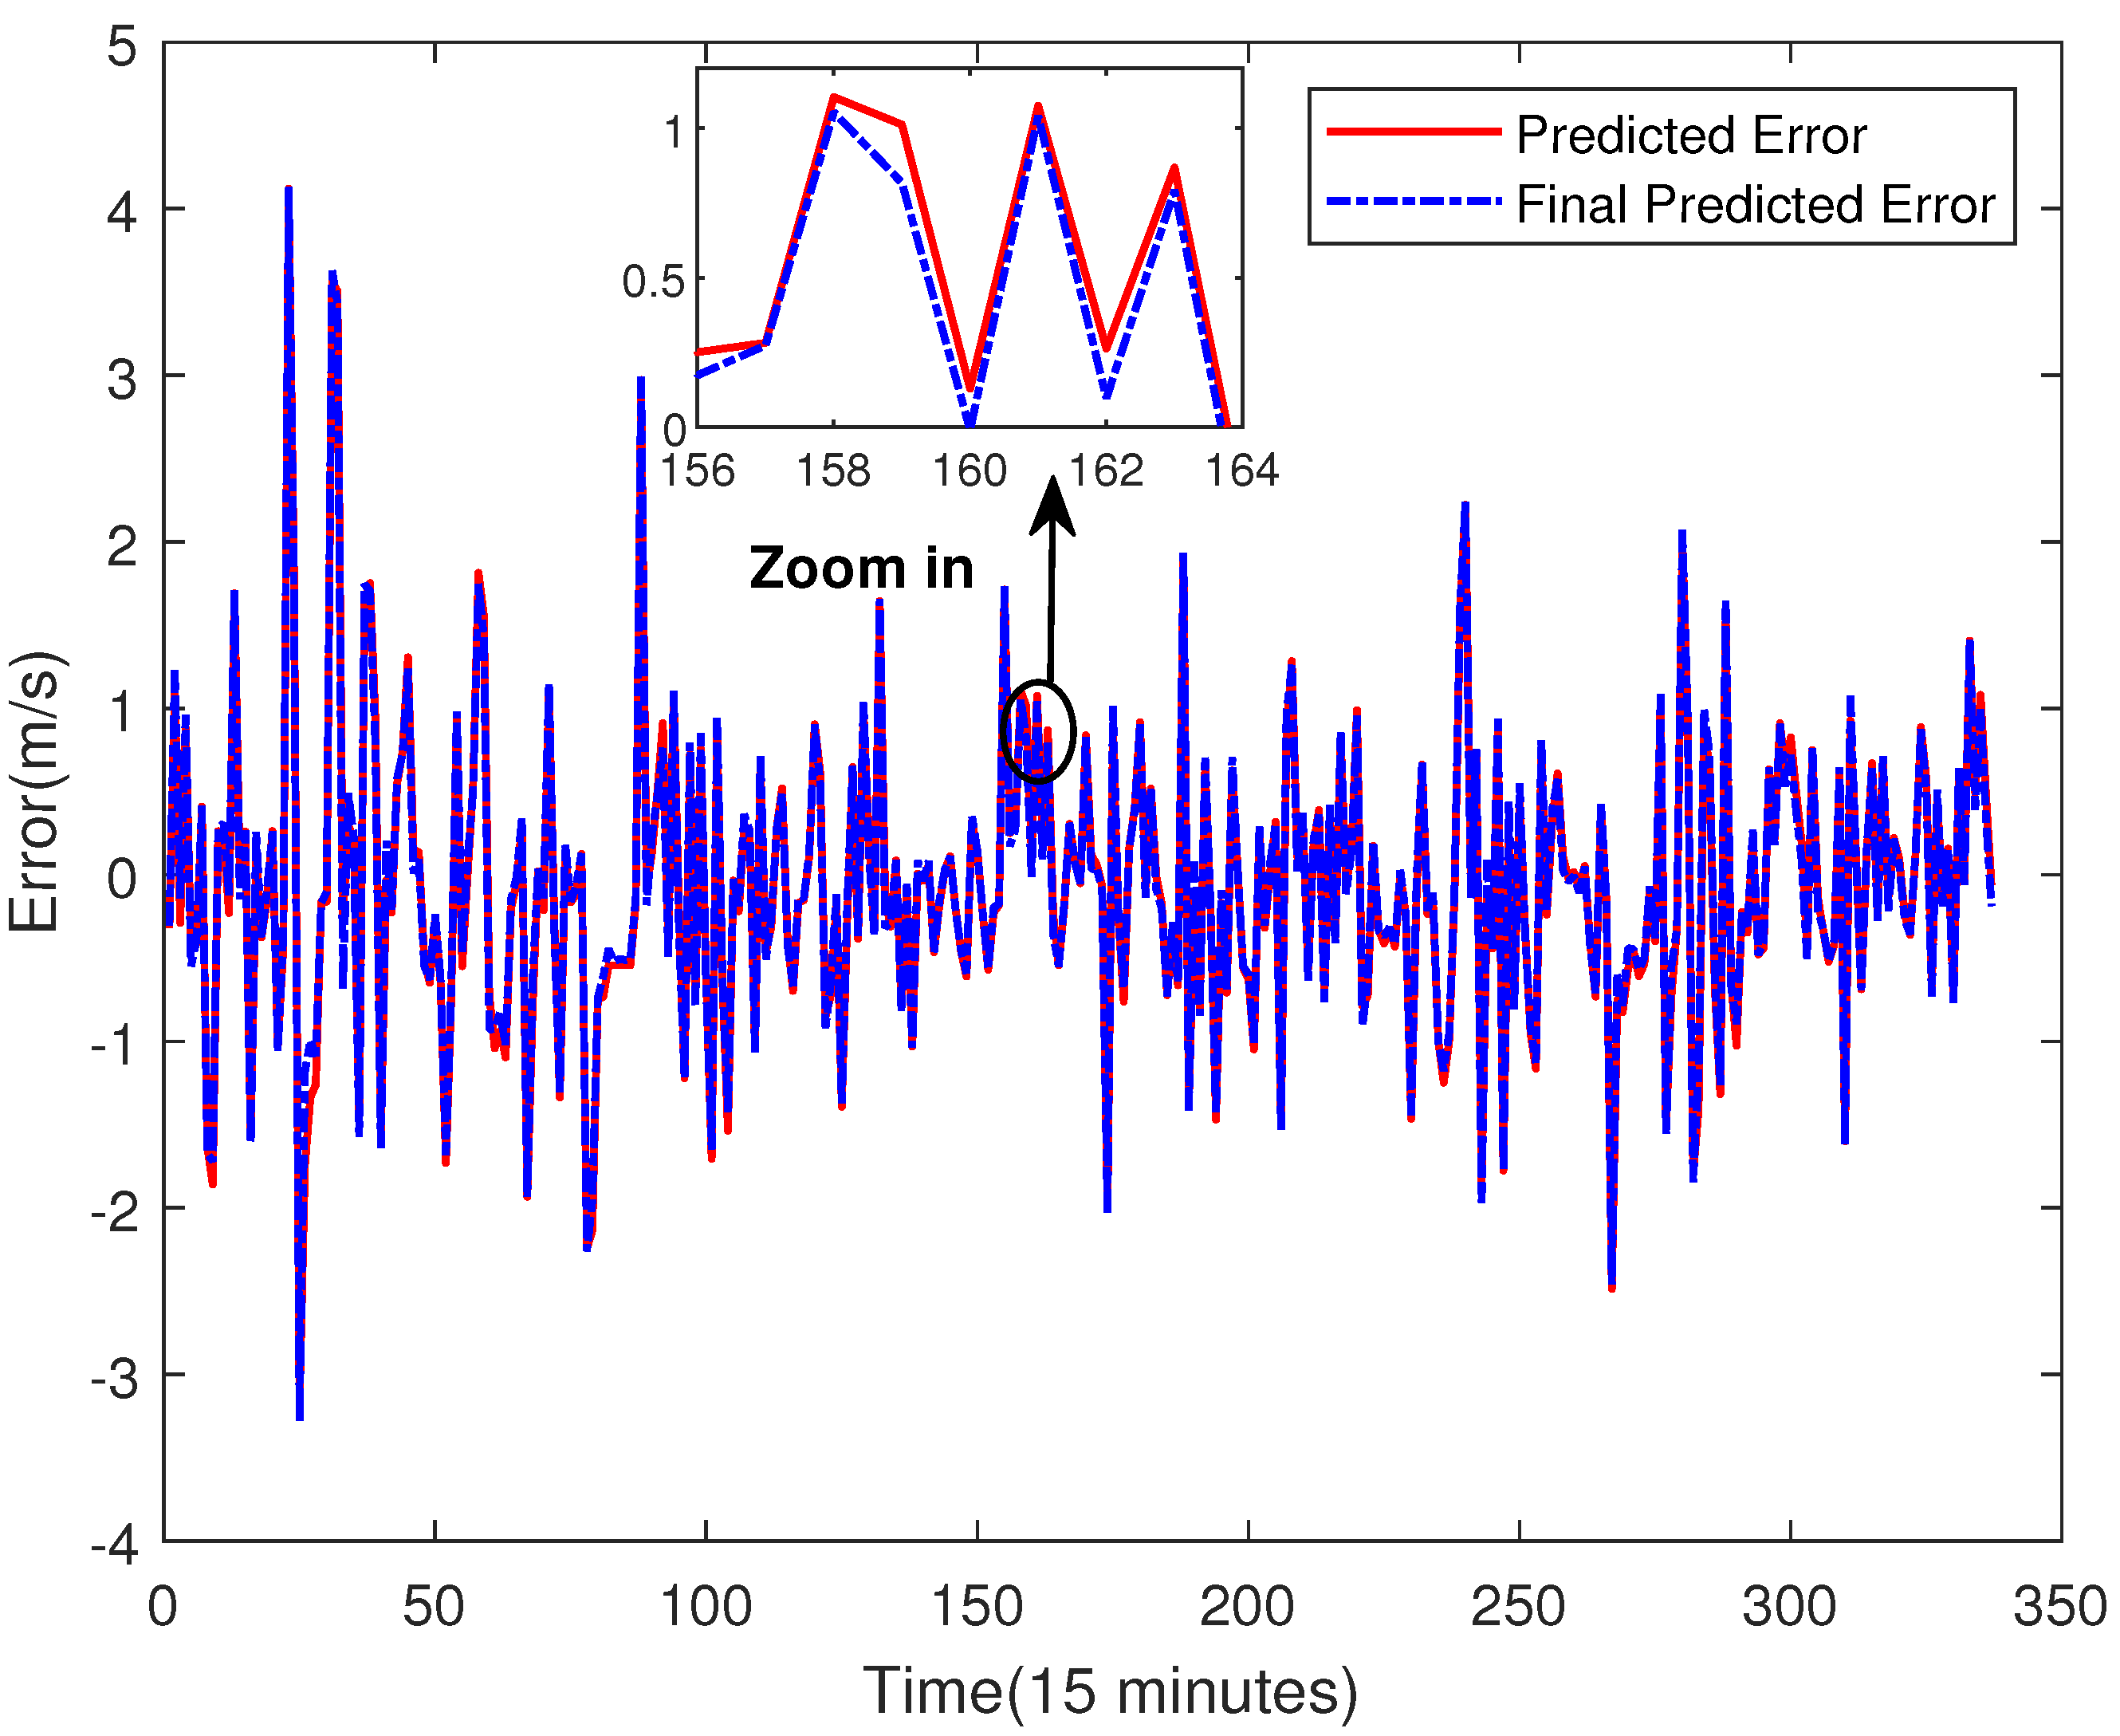
Compared with the direct prediction of wind speed (shown as Figure 5), Figure 12 shows that the RMSE of the prediction result is 0.89609, which is smaller than the 0.91226 of the prediction result from Figure 5. Figure 13 is the error comparison of Figure 5 and Figure 12, the result shows the prediction error has decreased, and the overall prediction result after ELM error compensation has been improved. Although the error compensation value is very small, it can also further narrow the gap between the predicted value and the true value. Therefore, the overall prediction effect can be improved.
Figure 13.
The Error Comparison.
4.3. Comparison Studies of Error Compensation
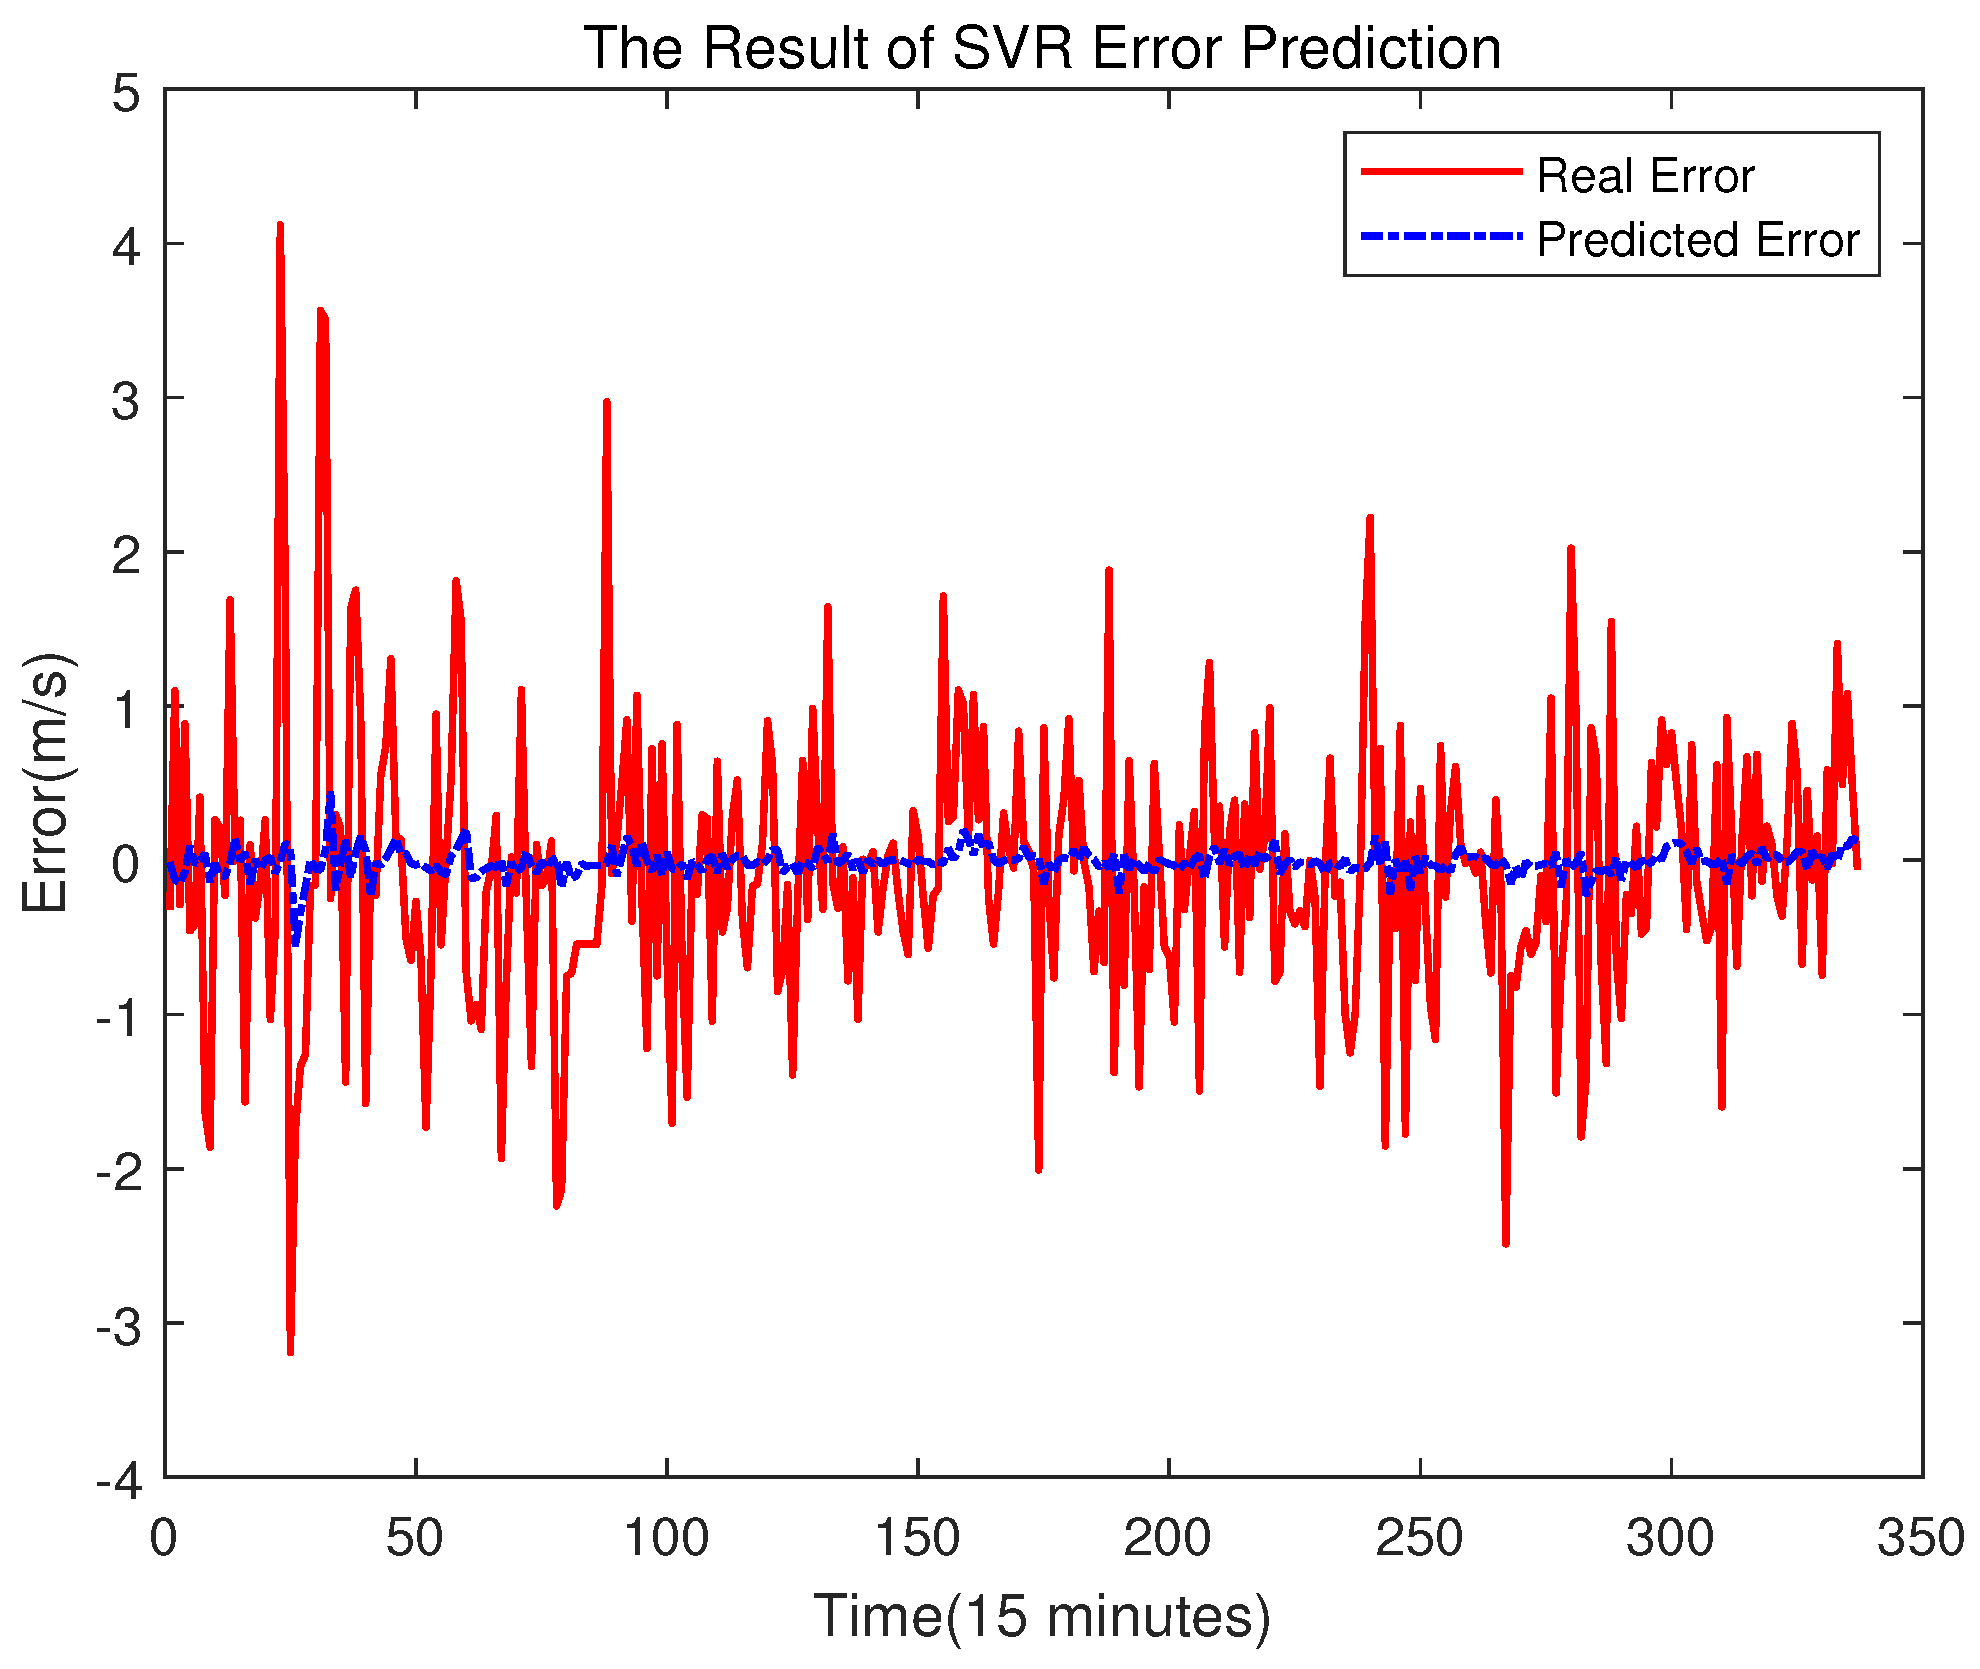
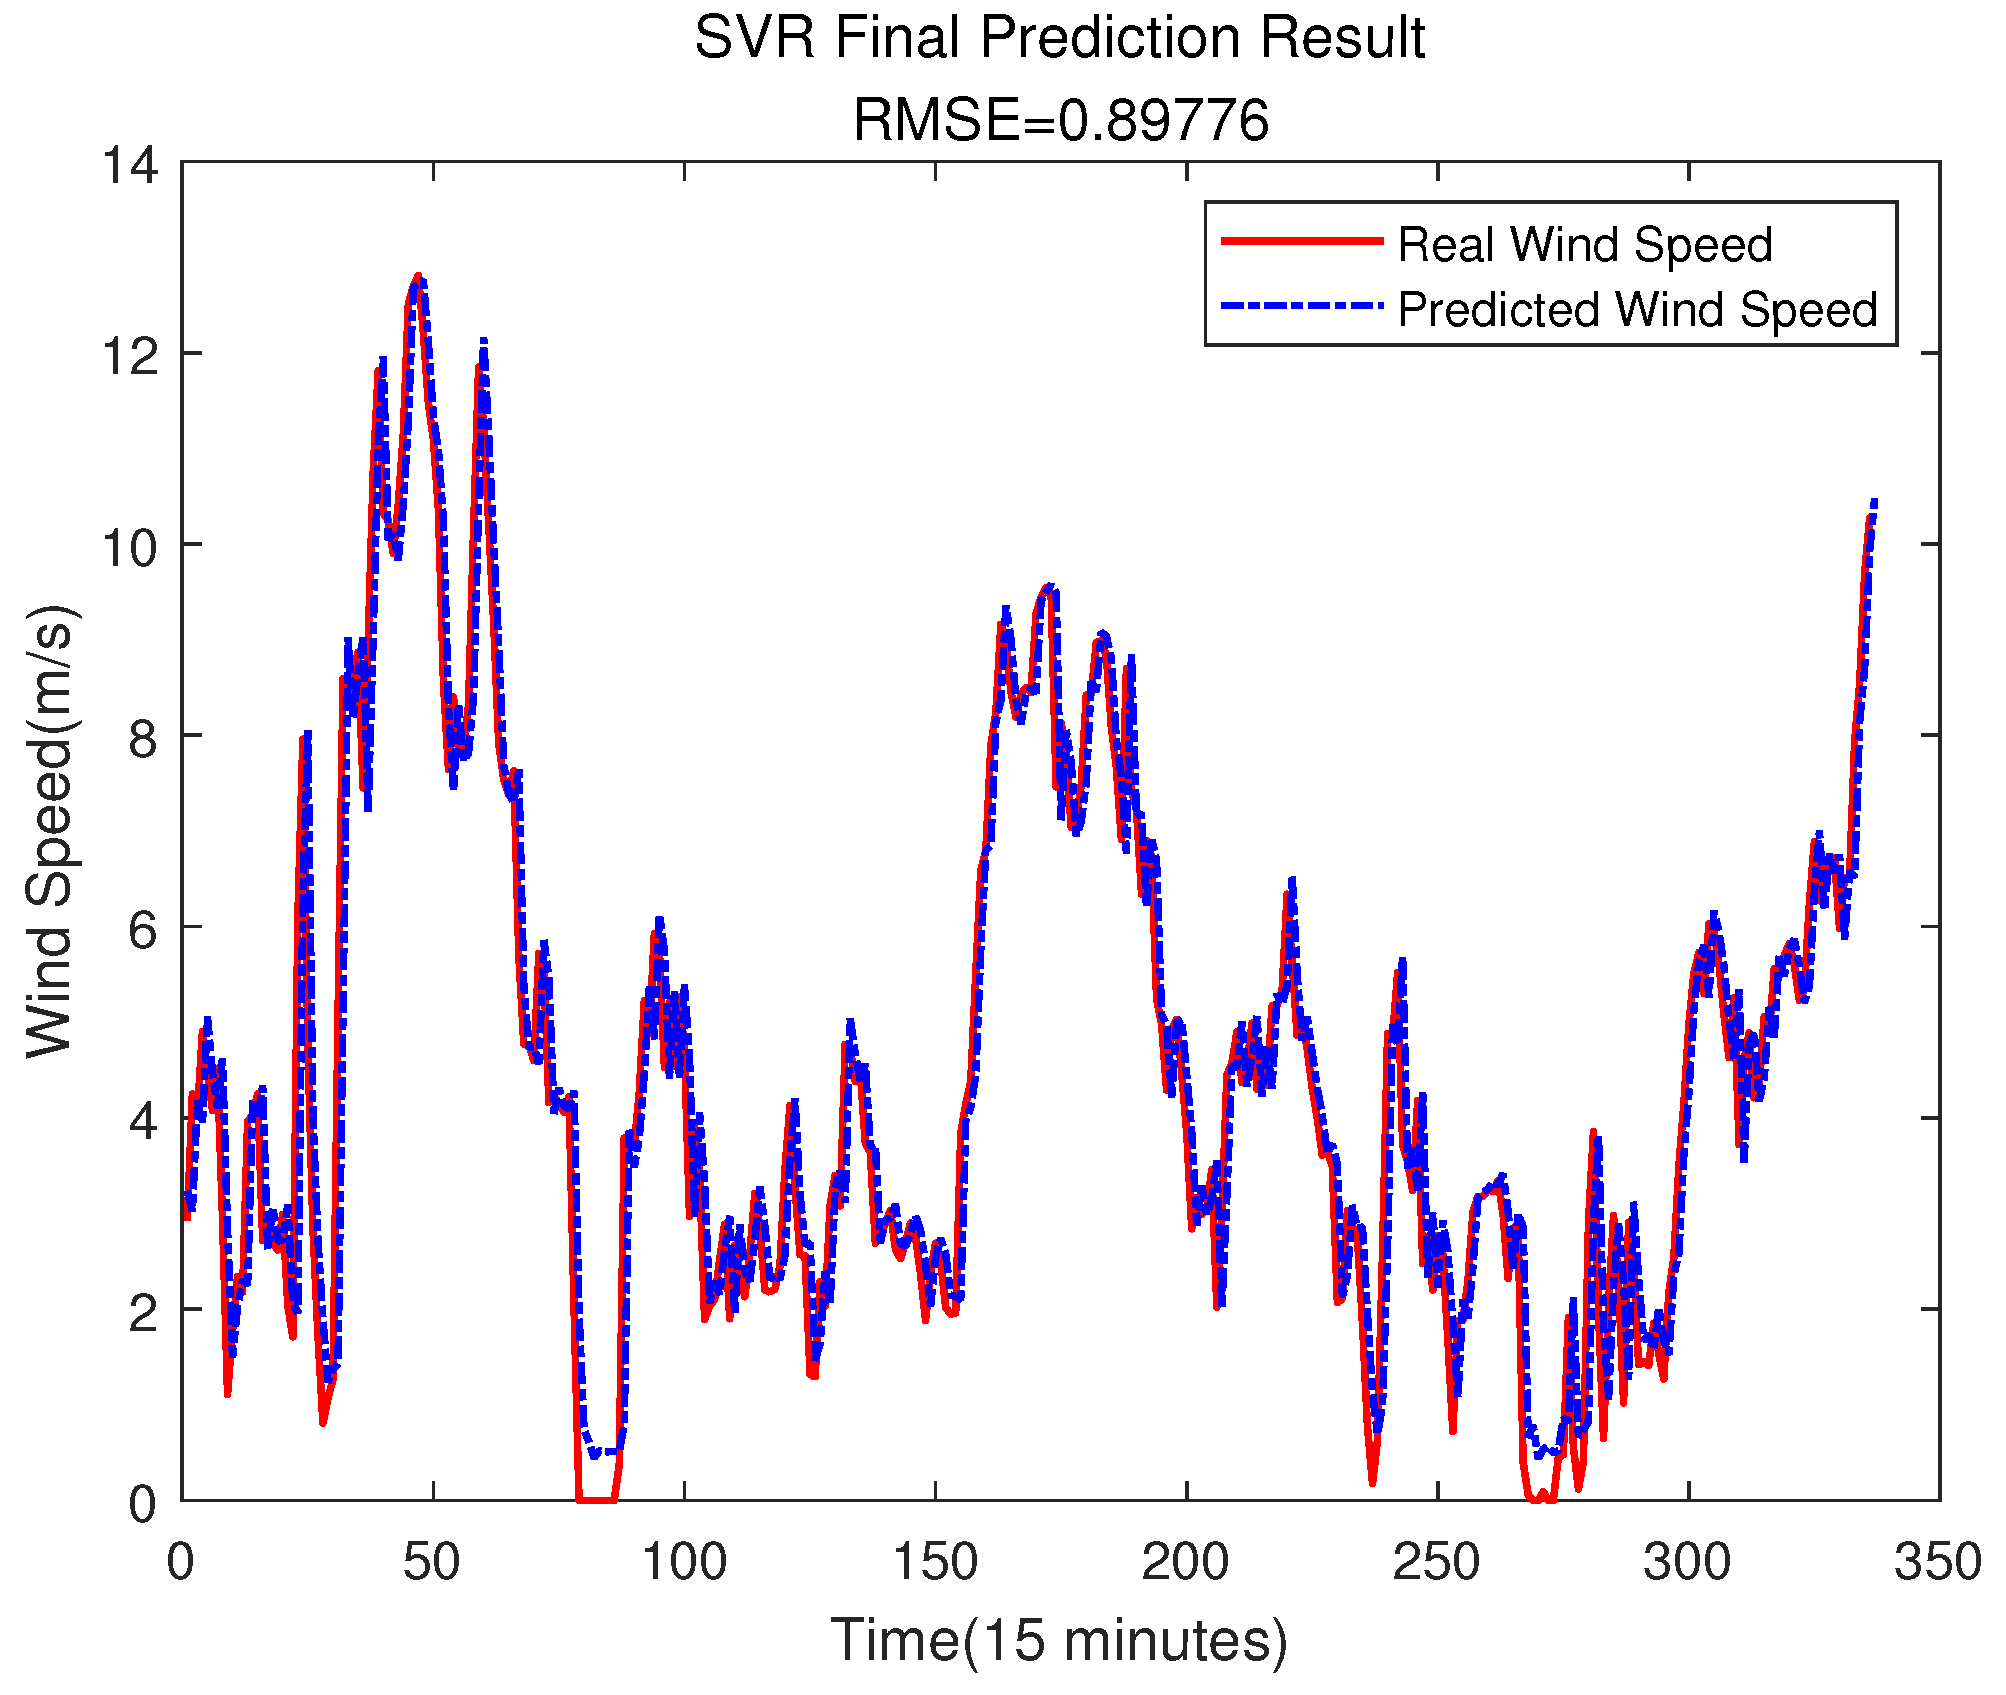
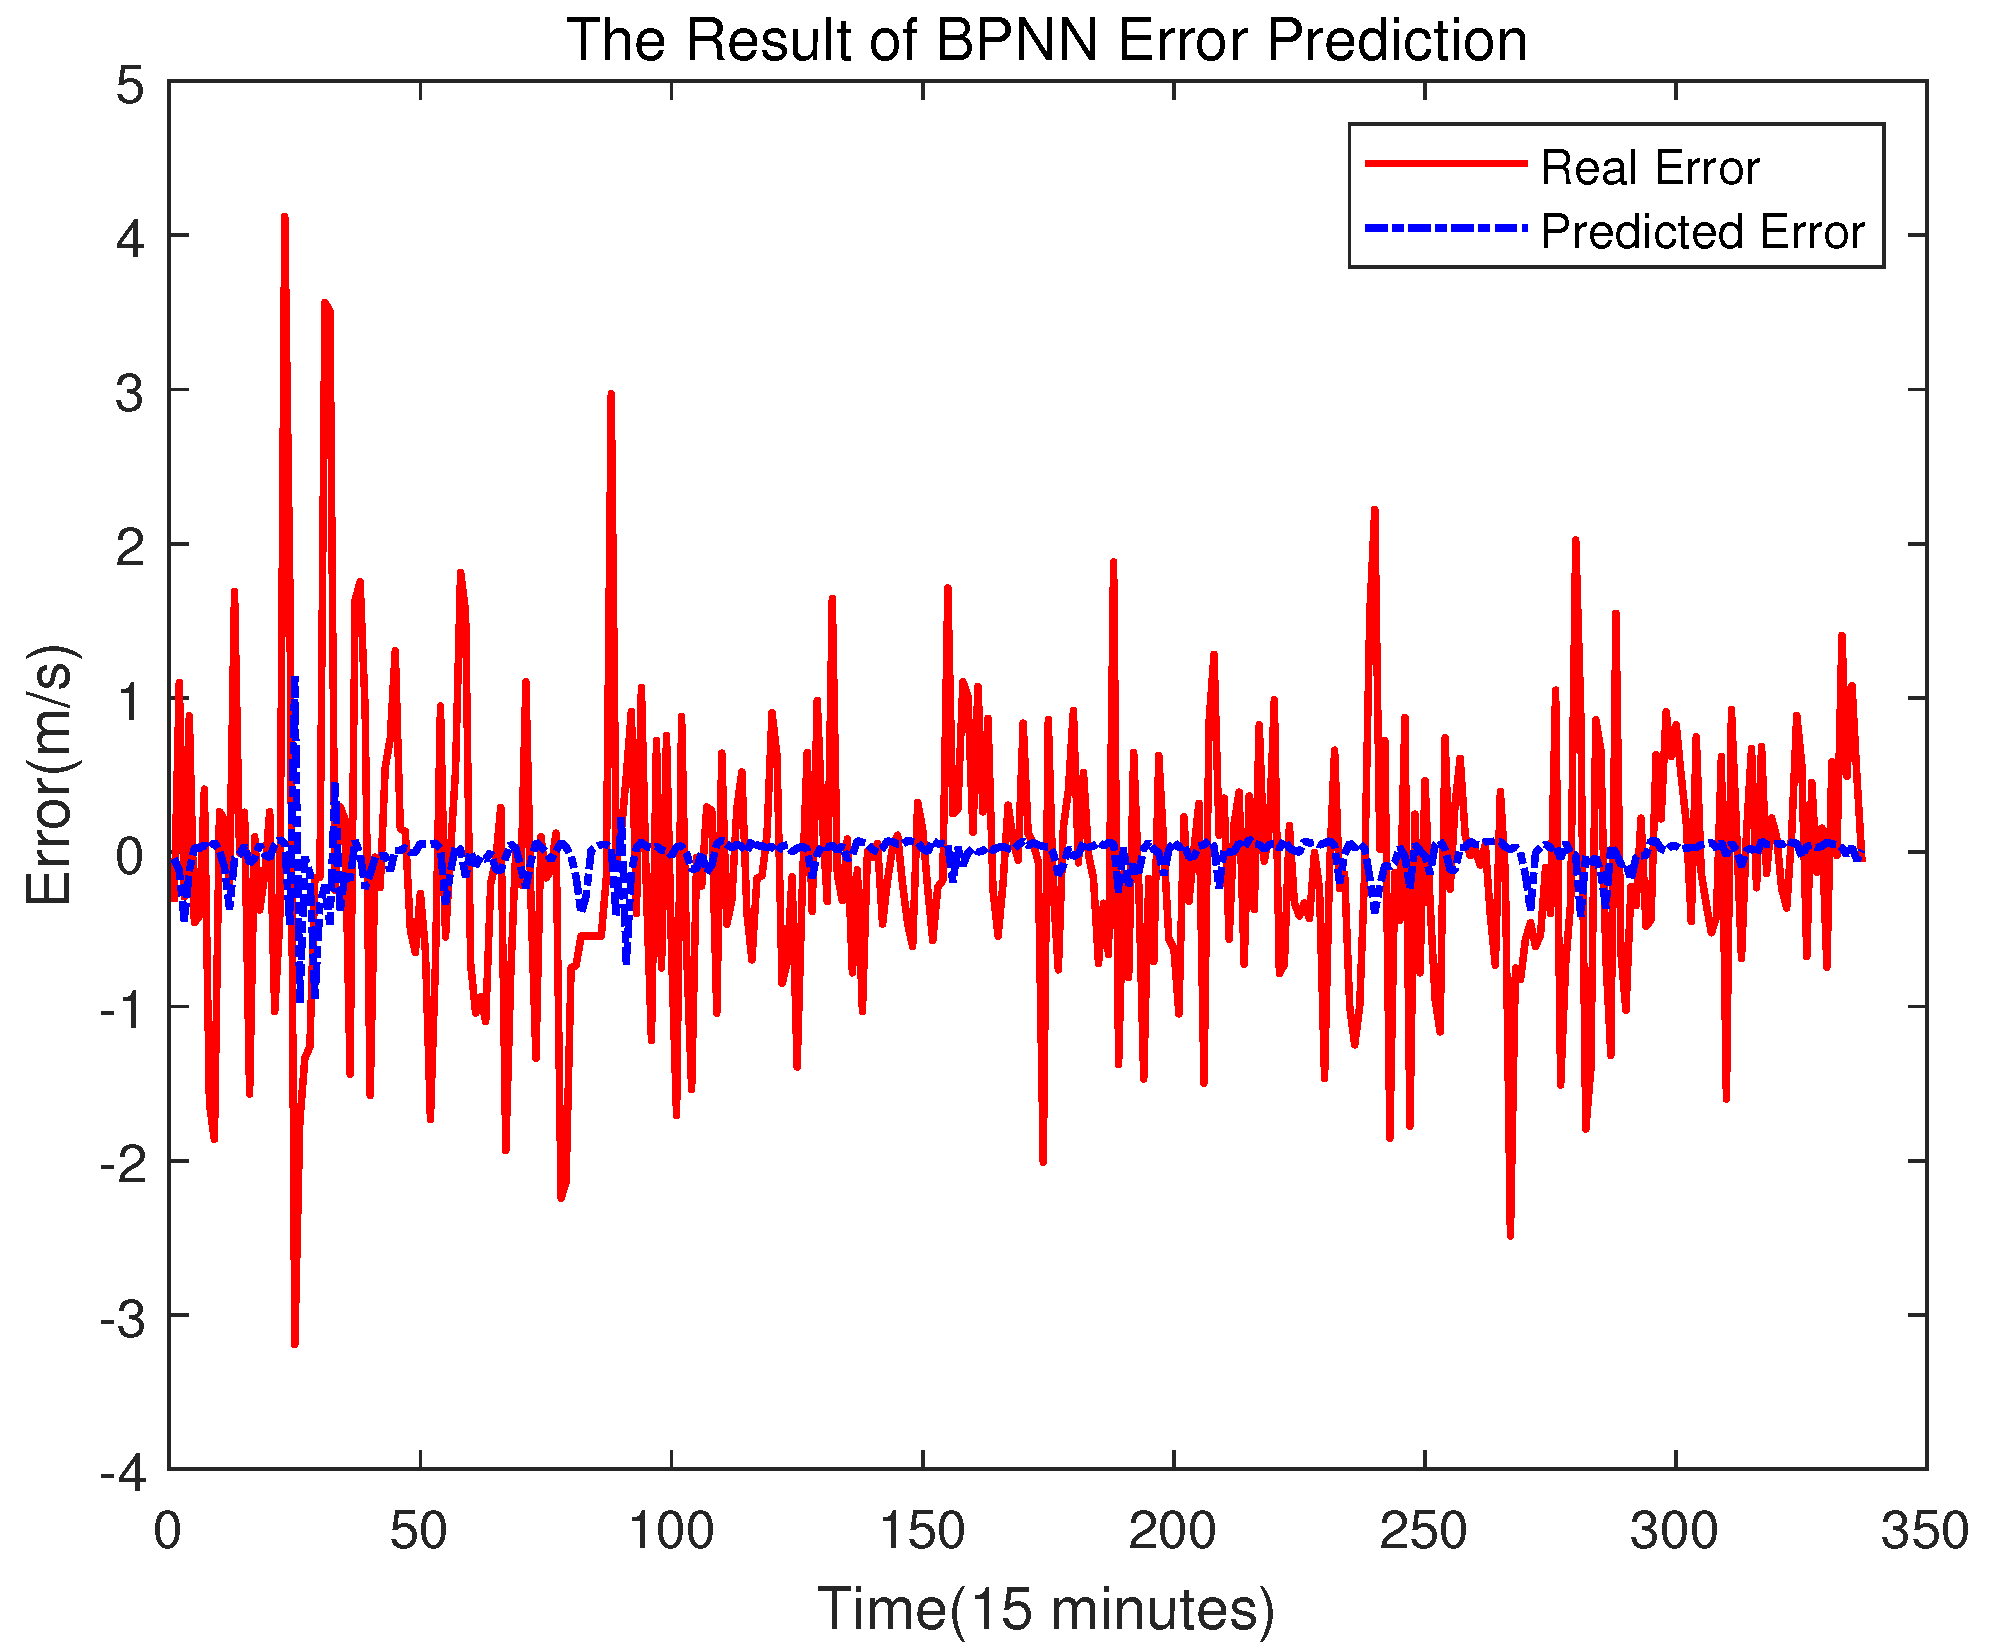
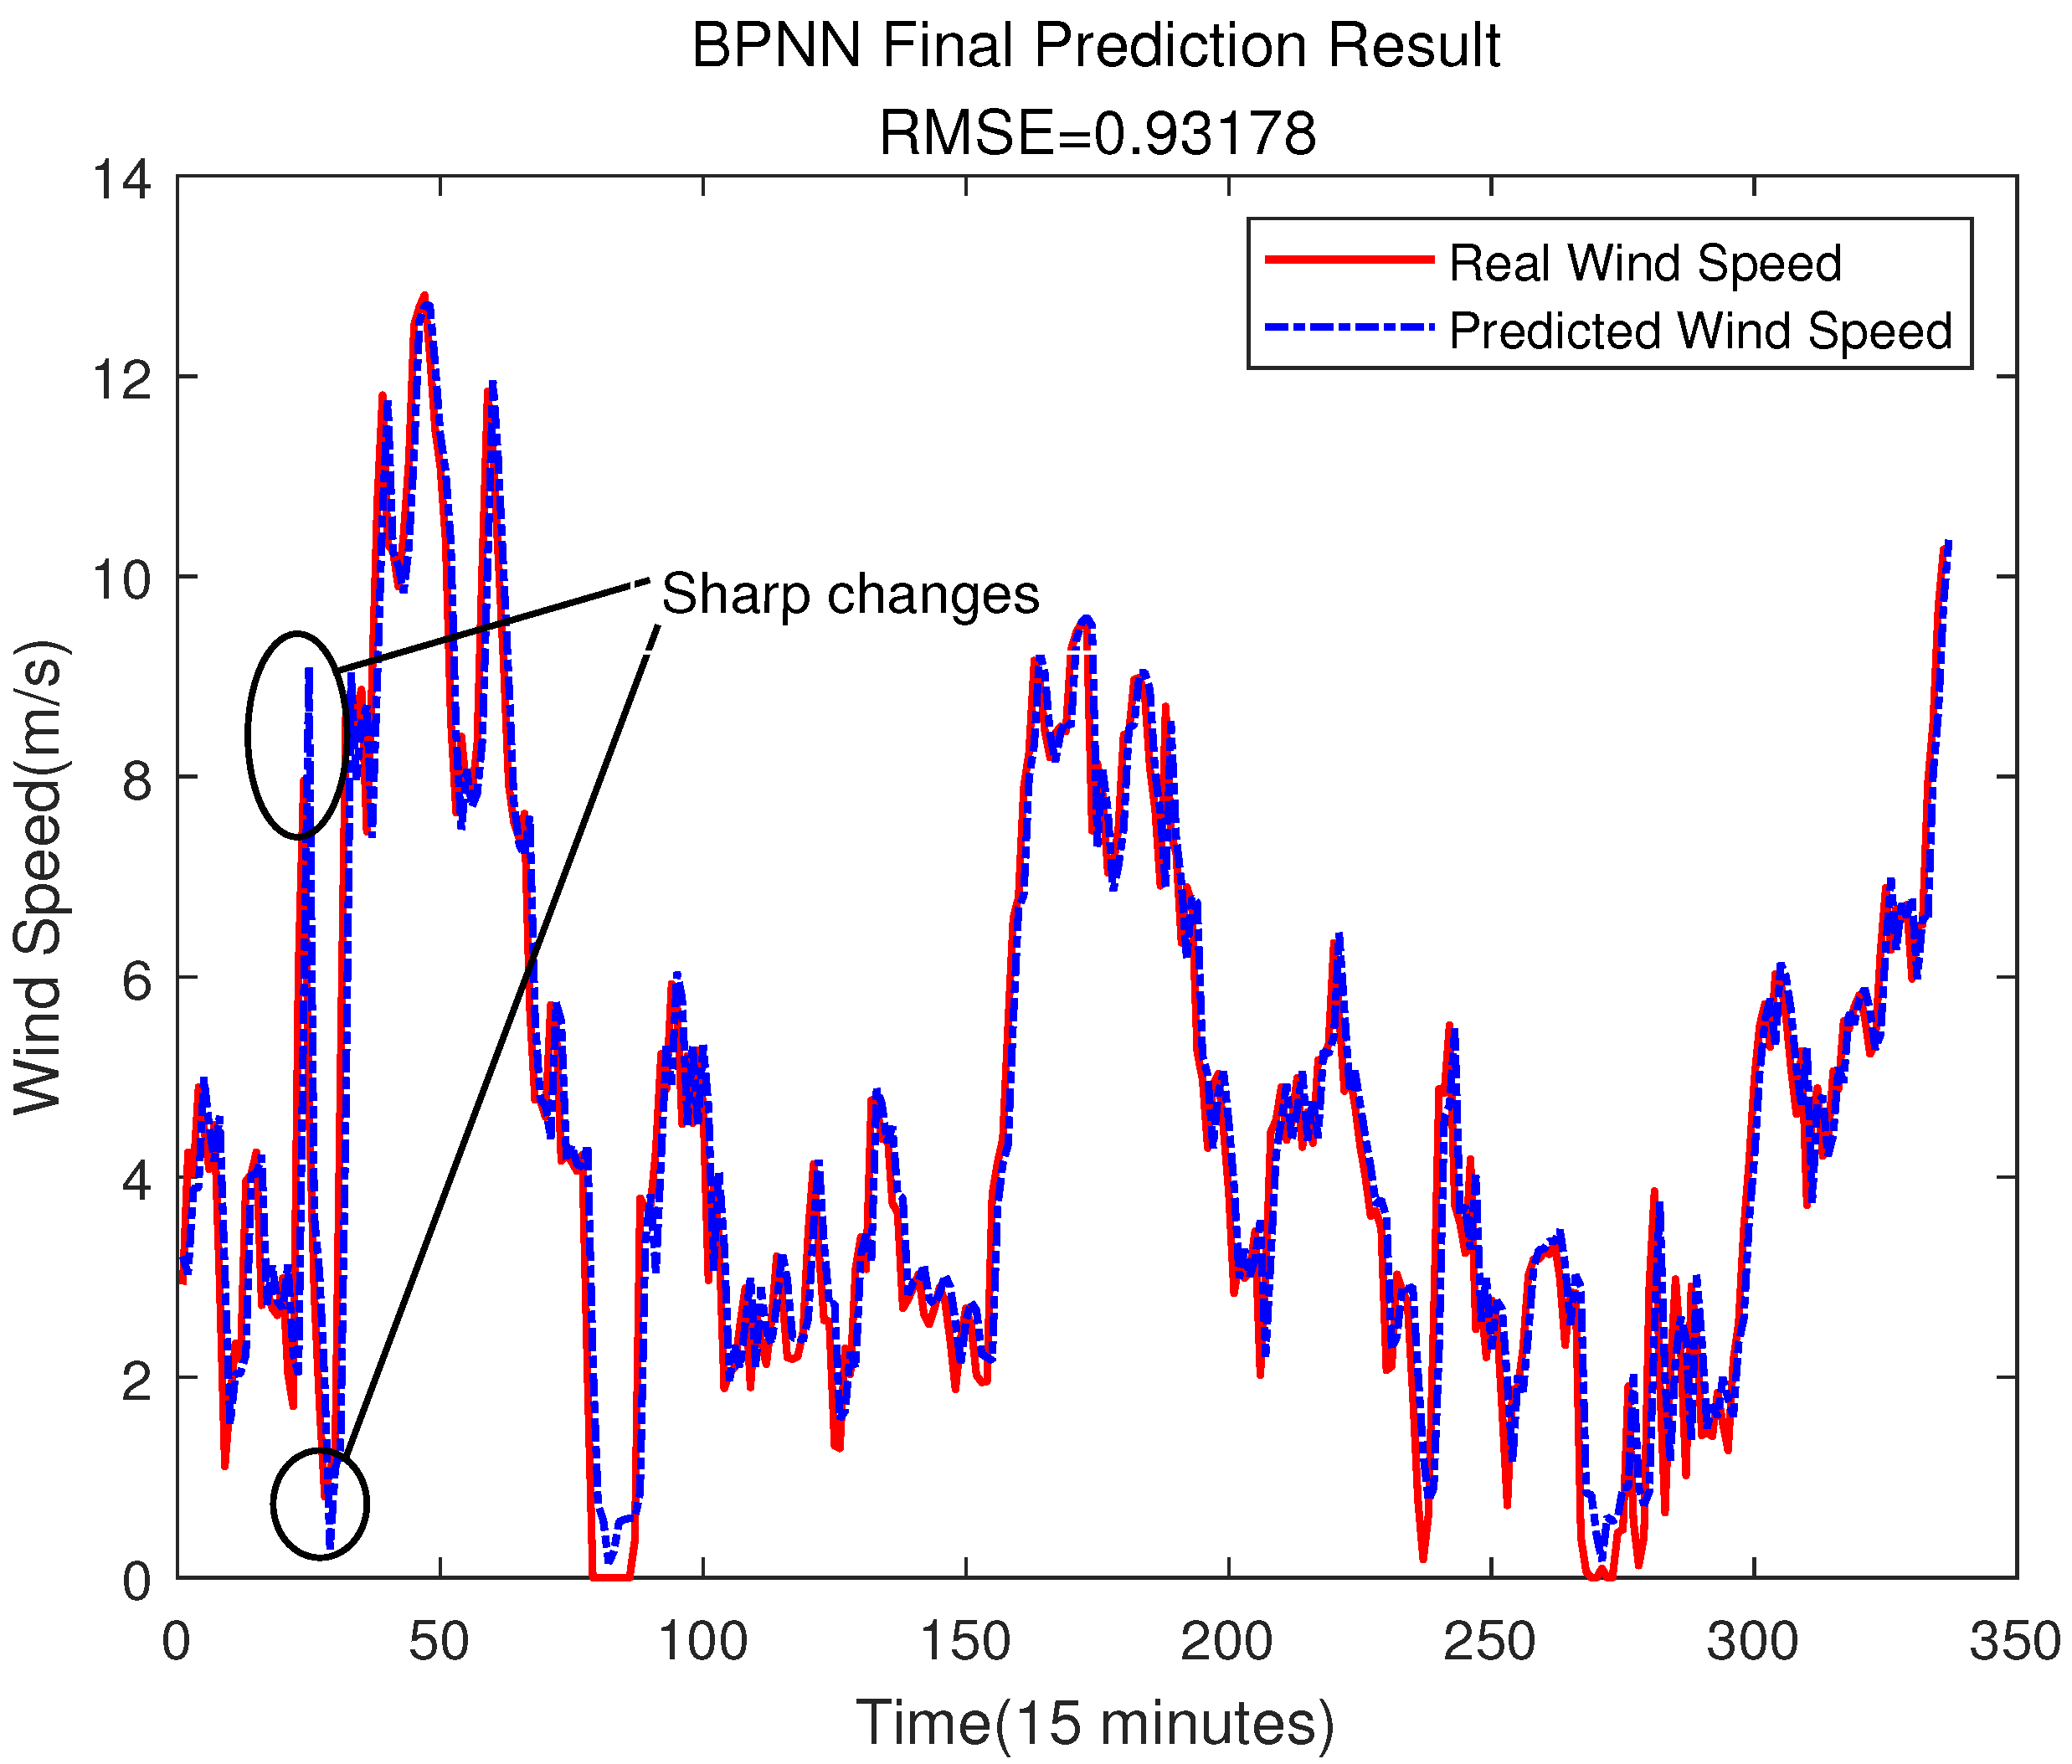
In order to prove the better effect of error prediction using ELM, this section compares the error prediction of SVR and BPNN. The training set of SVR and BPNN is the same as that of ELM. The results are shown in Figure 14, Figure 15, Figure 16 and Figure 17.
Figure 14.
Error Prediction of SVR.
Figure 15.
The Final Prediction Result of SVR.
Figure 16.
Error Prediction of BPNN.
Figure 17.
The Final Prediction Result of BPNN.
In this paper, the kernel function of SVR is RBF, is 0.0039, and the penalty factor is 3.8855. The neural nodes and hidden layers of the BPNN are 10 and 2, respectively.
It can be seen from the above figure that neither the SVR nor the BPNN method can predict the error very well. In Figure 15, the accuracy of the final prediction result after SVR error compensation is also improved compared to Figure 5, with the RMSE being 0.89776, but it is still slightly higher than the result of the ELM error compensation of 0.89609 in Figure 12. For the BPNN error compensation technique, there are always some sharp changes in the predicted wind speed, such as at time 25 and 29. This obviously will reduce the wind speed prediction accuracy.
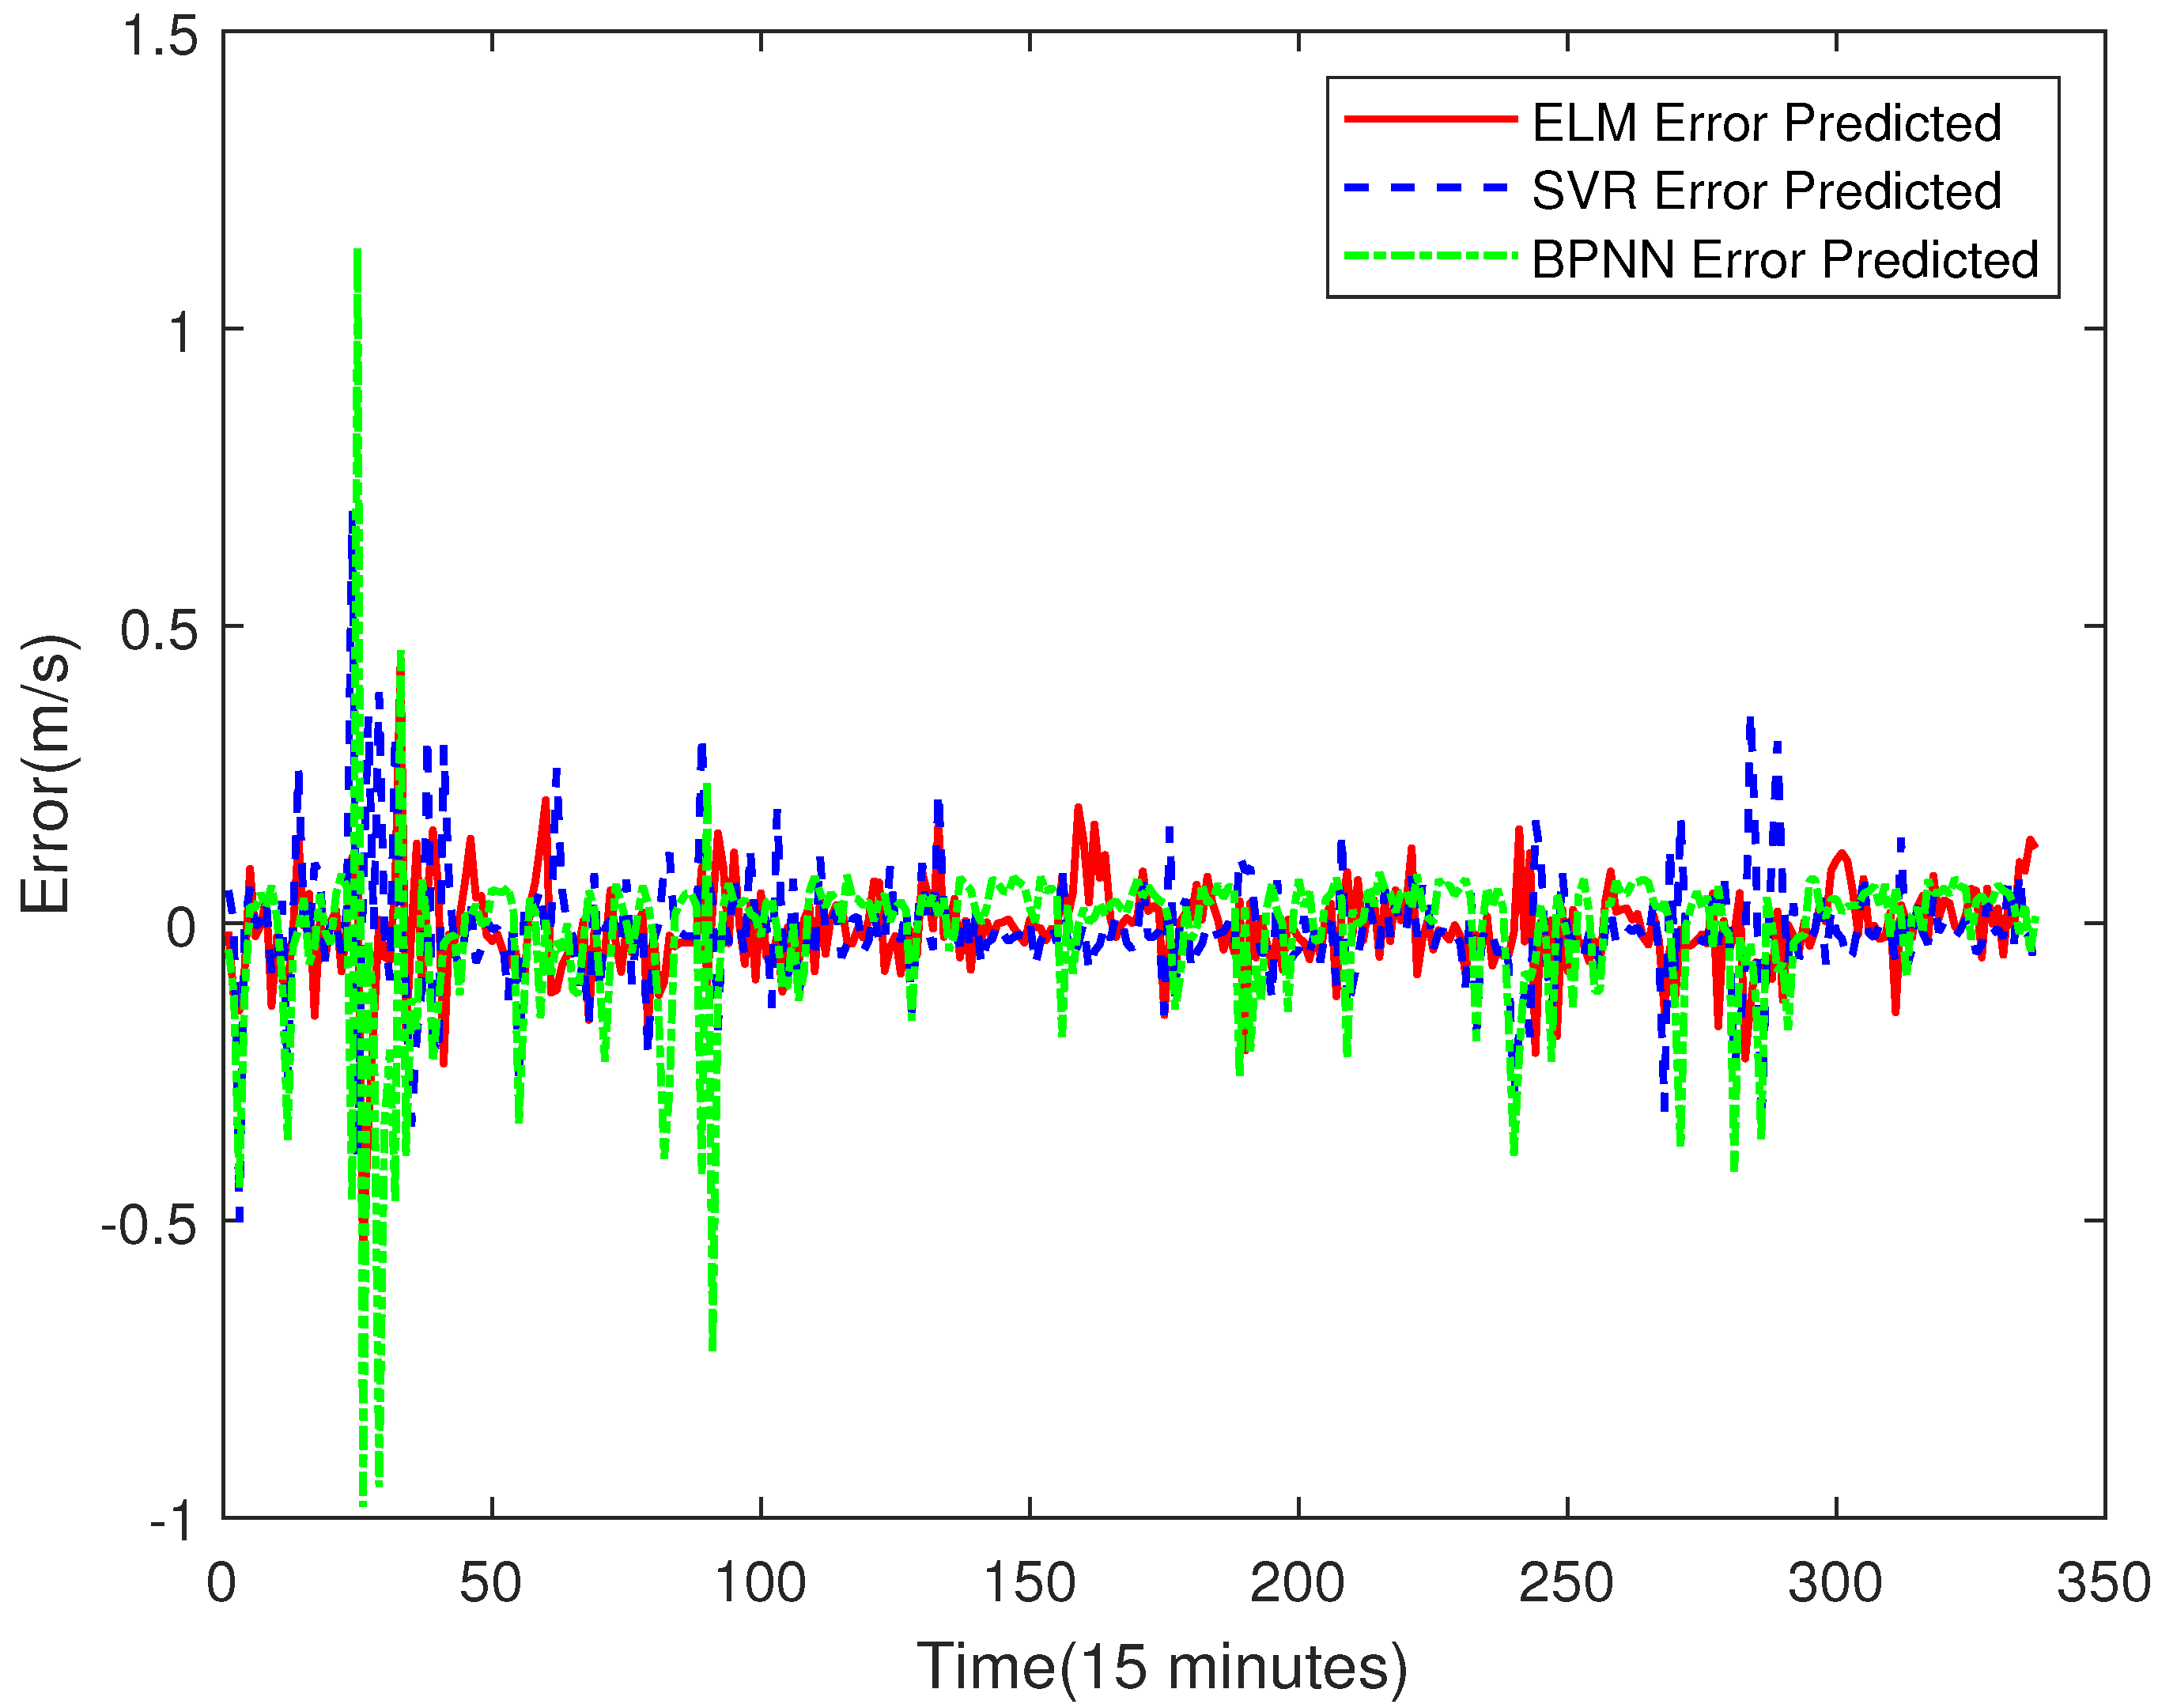
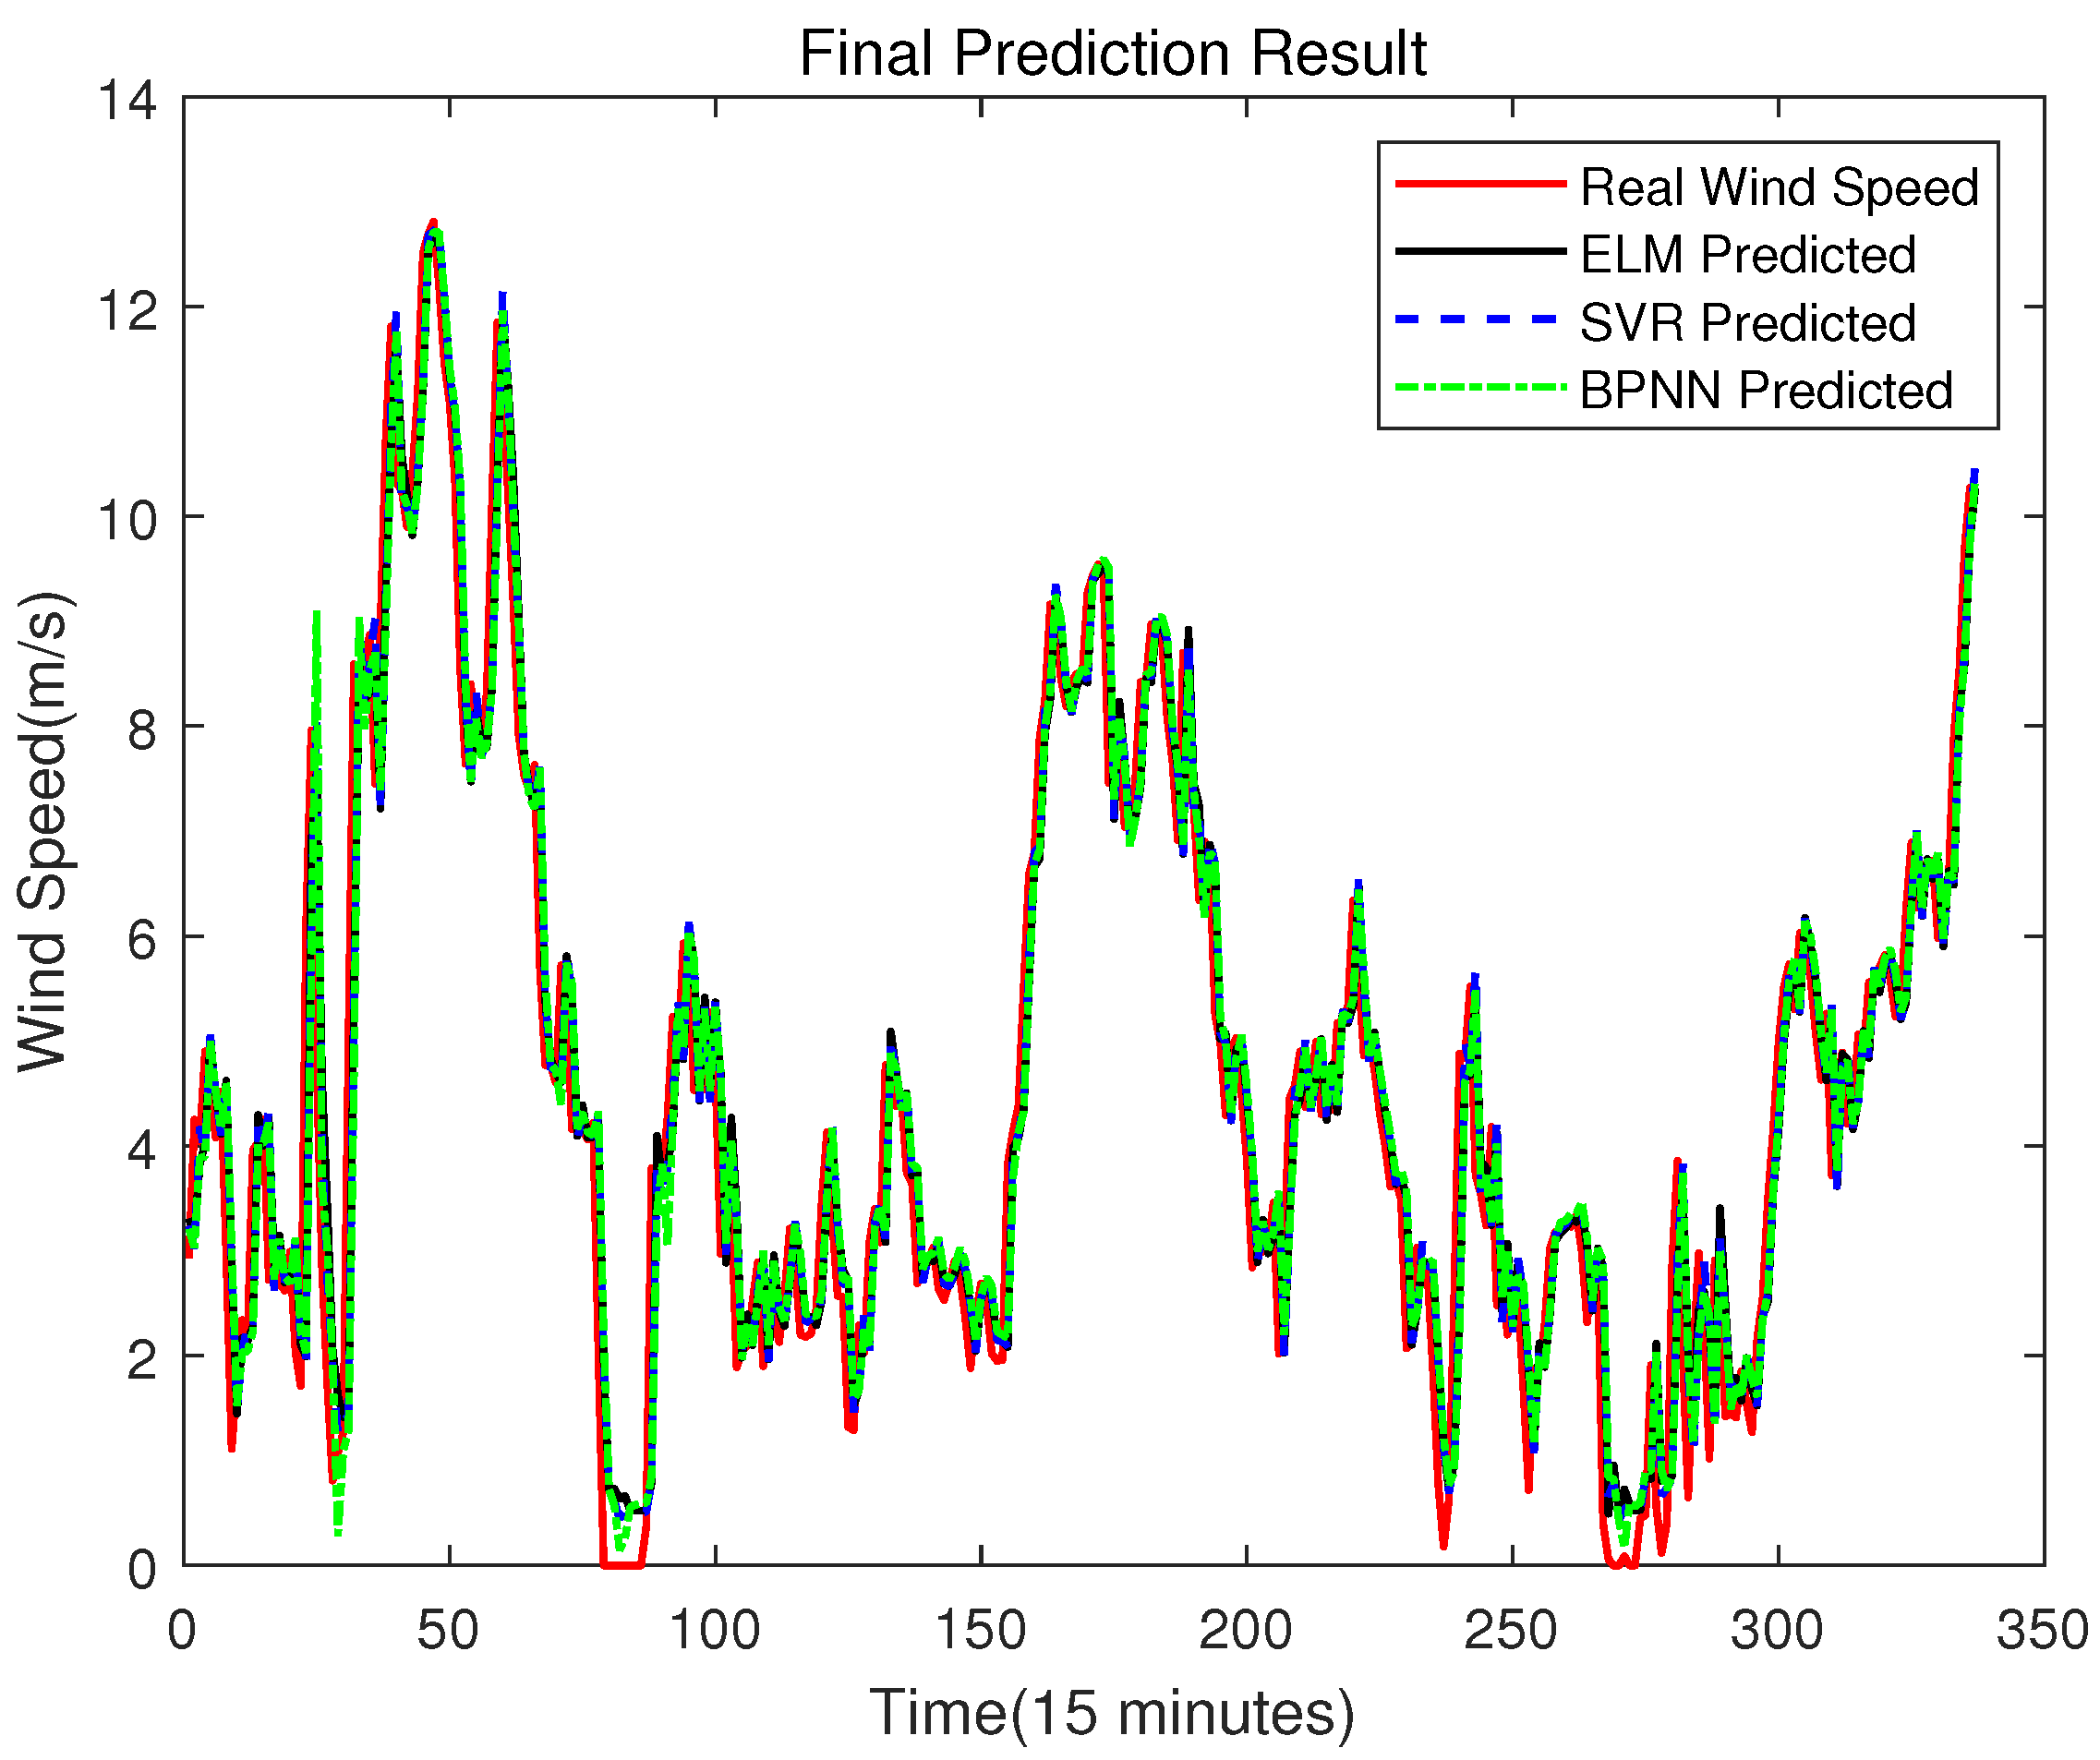
From Figure 18, the mean values of the error prediction results of ELM, SVR and BPNN models are , and , respectively, which indicates that the volatility of the BPNN prediction result is the highest, and the ELM prediction result is the smallest. In other words, the prediction result of the ELM error compensation is more accurate than that of the other two models. The final prediction result of ELM, SVR and BPNN after error compensation are shown in Figure 19.
Figure 18.
The Comparison of Error Prediction Results of ELM, SVR and BPNN.
Figure 19.
The Final Prediction Result of ELM, SVR and BPNN.
Table 3 shows the evaluation indicators of prediction performance through ELM, SVR and BPNN error compensation, and whether RMSE, or ELM is better than the other two methods. Therefore, it is reasonable to use ELM for error compensation prediction.
Table 3.
The RMSE and of ELM, SVR and BPNN.
5. Conclusions
In order to predict the univariate wind speed time series more accurately, this paper proposes a hybrid model based on ARMA-SVR to predict wind speed. ARMA is used to model the univariate series, and its PACF is obtained to guide the data division. Then, the divided data are used to train the SVR model to predict wind speed. This way can make full use of the original data without wasting machine performance, and it can improve the prediction effect. Then, in order to further improve the prediction accuracy, the error compensation method is adopted in this paper. Through a comparison of ELM, SVR and BPNN, it is proven that ELM is more suitable for error compensation prediction.
With the verification of real data, the ARMA-SVR-ELM hybrid model proposed in this paper can improve the accuracy of wind speed prediction compared to the direct forecasting method, and thus it can be applied in practice.
Meanwhile, there are still some areas worth improving in this study. For example, this study only uses historical wind speed time series to conduct the prediction task. How to use multi spatio-temporal scale features to achieve more accurate prediction results is a promising research direction.
Author Contributions
Methodology, X.J. and X.W.; Software, D.Z.; Validation, X.J. and X.W.; Investigation, X.J. and X.W.; Resources, Y.T., W.L. and L.X.; Data curation, D.Z.; Writing—review & editing, X.J. and D.Z.; Project administration, Y.T., W.L. and L.X. All authors have read and agreed to the published version of the manuscript.
Funding
This work was supported in part by the Shandong Provincial Nature Science Foundation of China under Grant ZR2021QF115, in part by the National Natural Science Foundation of China under Grant 62203249, in part by the Lixian Scholar Project of Qingdao University of Technology, and in part by the “20 New Universities” Project of Jinan City under Grant 202228077.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The data is unavailable due to privacy security.
Conflicts of Interest
The authors declare no conflict of interest.
Nomenclature
The following nomenclatures are used in this manuscript:
| X | Wind speed time series |
| Current value of wind speed time series | |
| Autoregressive parameter | |
| Moving average parameter | |
| p | Partial Autocorrelation Coefficient |
| q | Autocorrelation Coefficient |
| White nose of time t | |
| RBF kernel function | |
| Coefficient vector of SVR model | |
| b | Bias of SVR model |
| Center of kernel function | |
| C | Penalty factor of SVR |
| N | Number of Samples |
| Input data of SVR | |
| Output targets of SVR | |
| , | Slack variables of SVR |
| Loss coefficient of SVR | |
| K | Number of neurons of ELM |
| Random weights of ELM | |
| Deviation of ELM | |
| Output Layer Weights of ELM | |
| Sigmoid activation function | |
| The ith value of wind speed time series | |
| The ith estimate value of wind speed time series | |
| Average value of samples | |
| AC | Autocorrelation Functions |
| ACF | Autocorrelation Coefficient |
| ADF | Augmented Dickey-Fuller |
| AIC | Akaike Information Criterion |
| ARMA | Autoregressive Moving Average |
| BPNN | Backpropagation Neural Network |
| ELM | Extreme Learning Machine |
| PAC | Partial Autocorrelation Coefficient |
| PACF | Partial Autocorrelation Functions |
| RBF | Radical Basis Functions |
| SVR | Support Vector Regression |
References
- Wang, Y.; Hu, Q.; Li, L.; Foley, A.M.; Srinivasan, D. Approaches to wind power curve modeling: A review and discussion. Renew. Sustain. Energy Rev. 2019, 116, 109422. [Google Scholar] [CrossRef] [Scilit]
- Wang, Y.; Zou, R.; Liu, F.; Zhang, L.; Liu, Q. A review of wind speed and wind power forecasting with deep neural networks. Appl. Energy 2021, 304, 117766. [Google Scholar] [CrossRef] [Scilit]
- Wang, Y.; Li, Y.; Zou, R.; Foley, A.M.; Al Kez, D.; Song, D.; Hu, Q.; Srinivasan, D. Sparse heteroscedastic multiple spline regression models for wind turbine power curve modeling. IEEE Trans. Sustain. Energy 2020, 12, 191–201. [Google Scholar] [CrossRef] [Scilit]
- Yang, J.; Fang, L.; Song, D.; Su, M.; Yang, X.; Huang, L.; Joo, Y.H. Review of control strategy of large horizontal-axis wind turbines yaw system. Wind. Energy 2021, 24, 97–115. [Google Scholar] [CrossRef] [Scilit]
- Kou, L.; Li, Y.; Zhang, F.; Gong, X.; Hu, Y.; Yuan, Q.; Ke, W. Review on monitoring, operation and maintenance of smart offshore wind farms. Sensors 2022, 22, 2822. [Google Scholar] [CrossRef] [Scilit]
- Liu, Z.; Hajiali, M.; Torabi, A.; Ahmadi, B.; Simoes, R. Novel forecasting model based on improved wavelet transform, informative feature selection, and hybrid support vector machine on wind power forecasting. J. Ambient. Intell. Humaniz. Comput. 2018, 9, 1919–1931. [Google Scholar] [CrossRef] [Scilit]
- Wang, X.; Guo, P.; Huang, X. A review of wind power forecasting models. Energy Procedia 2011, 12, 770–778. [Google Scholar] [CrossRef] [Scilit]
- Jung, J.; Broadwater, R.P. Current status and future advances for wind speed and power forecasting. Renew. Sustain. Energy Rev. 2014, 31, 762–777. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Y.; Yang, J.; Wang, K.; Wang, Z. Wind power prediction considering nonlinear atmospheric disturbances. Energies 2015, 8, 475–489. [Google Scholar] [CrossRef] [Scilit]
- Jiao, X.; Zhou, X.; Yang, Q.; Zhang, Z.; Liu, W.; Zhao, J. An improved optimal torque control based on estimated wind speed for wind turbines. In Proceedings of the 2022 13th Asian Control Conference (ASCC), Jeju, Republic of Korea, 4–7 May 2022; pp. 2024–2029. [Google Scholar]
- Pandeya, S.P.; Zou, S.; Roh, B.M.; Xiao, X. Programmable Thermo-Responsive Self-Morphing Structures Design and Performance. Materials 2022, 15, 8775. [Google Scholar] [CrossRef] [Scilit]
- Xiao, X.; Roh, B.M.; Hamilton, C. Porosity management and control in powder bed fusion process through process-quality interactions. CIRP J. Manuf. Sci. Technol. 2022, 38, 120–128. [Google Scholar] [CrossRef] [Scilit]
- Xiao, X.; Chu, B.; Zhang, Z. Quality Quantification and Control via Novel Self-Growing Process-Quality Model of Parts Fabricated by LPBF Process. Materials 2022, 15, 8520. [Google Scholar] [CrossRef] [Scilit]
- Tang, X.; Yang, Q.; Wang, K.; Stoevesandt, B.; Sun, Y. Optimisation of wind farm layout in complex terrain via mixed-installation of different types of turbines. IET Renew. Power Gener. 2018, 12, 1065–1073. [Google Scholar] [CrossRef] [Scilit]
- Box, G.E.; Jenkins, G.M.; Reinsel, G.C.; Ljung, G.M. Time Series Analysis: Forecasting and Control; John Wiley & Sons: Hoboken, NJ, USA, 2015. [Google Scholar]
- de Oliveira, J.F.; Silva, E.G.; de Mattos Neto, P.S. A hybrid system based on dynamic selection for time series forecasting. IEEE Trans. Neural Networks Learn. Syst. 2021, 33, 3251–3263. [Google Scholar] [CrossRef] [Scilit]
- Xiao, X.; Waddell, C.; Hamilton, C.; Xiao, H. Quality Prediction and Control in Wire Arc Additive Manufacturing via Novel Machine Learning Framework. Micromachines 2022, 13, 137. [Google Scholar] [CrossRef] [Scilit]
- Narayanan, S.; Zhang, Y.; Aslani, F. Prediction Models of Shielding Effectiveness of Carbon Fibre Reinforced Cement-Based Composites against Electromagnetic Interference. Sensors 2023, 23, 2084. [Google Scholar] [CrossRef] [Scilit]
- Fang, S.; Zhang, B.; Hu, J. Improved Mask R-CNN Multi-Target Detection and Segmentation for Autonomous Driving in Complex Scenes. Sensors 2023, 23, 3853. [Google Scholar] [CrossRef] [Scilit]
- Liu, M.; Cao, Z.; Zhang, J.; Wang, L.; Huang, C.; Luo, X. Short-term wind speed forecasting based on the Jaya-SVM model. Int. J. Electr. Power Energy Syst. 2020, 121, 106056. [Google Scholar] [CrossRef] [Scilit]
- Hua, L.; Zhang, C.; Peng, T.; Ji, C.; Nazir, M.S. Integrated framework of extreme learning machine (ELM) based on improved atom search optimization for short-term wind speed prediction. Energy Convers. Manag. 2022, 252, 115102. [Google Scholar] [CrossRef] [Scilit]
- Alghofaili, Y.; Rassam, M.A. A Dynamic Trust-Related Attack Detection Model for IoT Devices and Services Based on the Deep Long Short-Term Memory Technique. Sensors 2023, 23, 3814. [Google Scholar] [CrossRef] [Scilit]
- Liu, M.D.; Ding, L.; Bai, Y.L. Application of hybrid model based on empirical mode decomposition, novel recurrent neural networks and the ARIMA to wind speed prediction. Energy Convers. Manag. 2021, 233, 113917. [Google Scholar] [CrossRef] [Scilit]
- Liu, H.; Yang, R.; Duan, Z. Wind speed forecasting using a new multi-factor fusion and multi-resolution ensemble model with real-time decomposition and adaptive error correction. Energy Convers. Manag. 2020, 217, 112995. [Google Scholar] [CrossRef] [Scilit]
- Xu, X.; Hu, S.; Shi, P.; Shao, H.; Li, R.; Li, Z. Natural phase space reconstruction-based broad learning system for short-term wind speed prediction: Case studies of an offshore wind farm. Energy 2023, 262, 125342. [Google Scholar] [CrossRef] [Scilit]
- McLeod, A.I.; Li, W.K. Diagnostic checking ARMA time series models using squared-residual autocorrelations. J. Time Ser. Anal. 1983, 4, 269–273. [Google Scholar] [CrossRef] [Scilit]
- Sun, Y.; Li, L.L.; Huang, X.S.; Duan, C.Y. Short-term wind speed forecasting based on optimizated support vector machine. Appl. Mech. Mater. 2013, 300, 189–194. [Google Scholar] [CrossRef] [Scilit]
- Jiao, X.; Yang, Q.; Xu, B. Hybrid Intelligent Feedforward-Feedback Pitch Control for VSWT with Predicted Wind Speed. IEEE Trans. Energy Convers. 2021, 36, 2770–2781. [Google Scholar] [CrossRef] [Scilit]
- Yin, H.; Dong, Z.; Chen, Y.; Ge, J.; Lai, L.L.; Vaccaro, A.; Meng, A. An effective secondary decomposition approach for wind power forecasting using extreme learning machine trained by crisscross optimization. Energy Convers. Manag. 2017, 150, 108–121. [Google Scholar] [CrossRef] [Scilit]
- Hyndman, R.J. Better ACF and PACF plots, but no optimal linear prediction. Electron. J. Stat. 2014. [Google Scholar] [CrossRef]




















Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2023 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).