


Abstract
We discuss several limiting degree distributions for a class of homogeneous random graphs, known as random threshold graphs, in the many node regime. This analysis is carried out under a weak assumption on the distribution of the underlying fitness variable. This assumption, which is satisfied by the exponential distribution, determines a natural scaling under which the following limiting results are shown: the nodal degree distribution, i.e., the distribution of any node, converges in distribution to a limiting pmf. However, for each , the fraction of nodes with degree d converges only in distribution to a non-degenerate random variable (whose distribution depends on d), and not in probability to the aforementioned limiting nodal pmf as is customarily expected. The distribution of is identified only through its characteristic function. Implications of this result include the following: (i) the empirical node distribution may not be used either as a proxy for or estimate of the limiting nodal pmf; (ii) even in homogeneous graphs, the network-wide degree distribution and the nodal degree distribution may capture vastly different information; and (iii) random threshold graphs with exponential distributed fitness do not provide an alternative scale-free model to the Barabási–Albert model as was argued by some authors; the two models cannot be meaningfully compared in terms of their degree distributions.
1. Introduction
Graphs as network models are routinely studied through their degree distributions, and much of the attention has focused on the empirical degree distribution that records the fractions of nodes with a given degree value. This distribution, which is easy to obtain from network measurements, has been found in many networks to obey a power law [1] (Section 1.4): If the network comprises a large number n of nodes and if there are nodes with degree d among them, then the data reveals a behavior of the form
for some in the range (although there are occasional exceptions) and [2,3]. See the monograph [1] (Section 4.2) for an introductory discussion and references, and the paper by Clauset et al. [4] for a principled statistical framework; see also the more recent paper by Voitalov et al. [5]. Statements such as (1) are usually left somewhat vague as the range for d is never carefully specified (in relation to n); networks where (1) was observed are often said to be scale-free.
The Barabási–Albert model came to prominence as the first random graph model to formally demonstrate the possibility of power law degree distribution in large networks [2]. The original Barabási–Albert model is a growth model which relies on the mechanism of preferential attachment—newly arriving nodes attach themselves to existing nodes with a probability proportional to their degrees at the time of arrival. As the number n of nodes increases, Bollobás et al. [6] proved that
where is the empirical degree distribution of the graph with n nodes, and the limiting pmf on has the power-tail behavior
Many generalizations of the Barabási–Albert model have been proposed over the years. Typically the convergence (2) still holds for some limiting pmf on with (3) replaced by () for some . The various models distinguish themselves from each other by their ability to achieve a value in a particular range [1] (Section 4.2).
Although in some contexts preferential attachment is a reasonable assumption, it is predicated on the degree of existing nodes being available to newly arriving nodes. There are many situations where this assumption is questionable, and where the creation of a link between two nodes may instead result from a mutual benefit based on their intrinsic attributes, e.g., authority, friendship, social success, wealth, etc. Random threshold graph models, which were proposed by Caldarelli et al. [7], incorporate this viewpoint in its simplest form as follows: let denote i.i.d. -valued random variables (rvs) with expressing the “fitness” level associated with node k. With n nodes and a threshold , the random threshold graph postulates that two distinct nodes i and j form a connection (and there is an undirected edge between them) if
Interest in random threshold graphs has been spurred by the following observations. The distribution of the degree rvs in (defined formally by (11)) is the same for all nodes. It is therefore appropriate to speak of the degree distribution of a node in , namely that of . Now consider the case when the fitness variable is exponentially distributed with parameter , and the threshold is scaled with the number n of nodes according to the scaling given by
In that setting, Fujihara et al. [8] have shown the distributional convergence
where the limiting rv D has pmf on with power-tail behavior
The result (5)–(6) has led some researchers [7,9] to conclude that random threshold graphs can model scale-free networks (with ) without having to resort to either a growth process or a preferential attachment mechanism, and as such they provide an alternative to the Barabási–Albert model. However, a moment of reflection should lead one to question this conclusion given the evidence available so far. Indeed, the statement (2) concerns an empirical degree distribution which is computed network-wide, whereas the convergence (5)–(6) addresses the distributional behavior of the degree of a single node, its distribution being identical across nodes.
A natural question is whether this discrepancy can be resolved in the large network limit. More precisely, for each , let denote the number of nodes in which have degree d, namely
In analogy with (2), when the fitness variable is exponentially distributed with parameter , it is certainly appropriate to wonder whether the convergence
takes place with the pmf being the one appearing at (5)–(6). Only then would random threshold graphs (under exponentially distributed fitness) be confirmed as a bona fide scale-free alternative model to the Barabási–Albert model (as described by (2)–(3)).
In this paper, for each , we show that there exists a non-degenerate-valued rv such that
where the scaling is the one defined at (4). In fact, we establish such a result for a very large class of fitness distributions (with the scaling modified accordingly). The non-degeneracy of the rv in (8) implies that (7) cannot hold, and random threshold graphs with exponential distributed fitness do not provide an alternative scale-free model to the Barabási–Albert model (as understood by (2)). Only the convergence (2) has meaning in the preferential attachment model while the convergence (5) has no equivalent there, the situation being reversed for random threshold graphs. The two models cannot be meaningfully compared in terms of their degree distributions! Thus, even in homogeneous graphs, the network-wide degree distribution and the nodal degree distribution may capture vastly different information. This issue was also investigated more broadly by the authors in the references [10,11,12]; see comments following Corollary 1.
We close with a summary of the contents of the paper: Random threshold graphs are introduced in Section 2 together with the needed notation and assumptions. As we consider situations that generalize the case of exponentially distributed fitness rvs, the scaling (4) is now replaced by a scaling satisfying Assumption 1. This assumption is determined by the probability distribution of , and ensures the convergence for some limiting rv D which is conditionally Poisson (given ) [Proposition 1]. Section 3 presents the main result of the paper [Theorem 1]. In the setting of Section 2, under Assumption 1, the distributional convergence (8) holds with a non-degenerate limit identified only through its characteristic function (35)–(36). A proof of Theorem 1 is given in Section 5 and is rooted in the method of moments [via Proposition 3 established in Section 6]. The main technical step is contained in Proposition 2; a proof of this multi-dimensional version of Proposition 1 is presented in several steps discussed in Section 7, Section 8, Section 9 and Section 10. In Section 4, we illustrate through limited simulations the failure of (7) and the validity of (8) in the case of random threshold graphs with exponentially distributed fitness.
2. Random Threshold Graphs
First, we detail some notation and conventions: The random variables (rvs) under consideration are all defined on the same probability triple . The construction of a sufficiently large probability triple carrying all needed rvs is standard and omitted in the interest of brevity. All probabilistic statements are made with respect to the probability measure , and we denote the corresponding expectation operator by . The notation (resp. ) is used to signify convergence in probability (resp. convergence in distribution) (under ) with n going to infinity; see the monographs [13,14,15] for definitions and properties. If E is a subset of , then denotes the indicator of the set E with the usual understanding that (resp. ) if (resp. ). The symbol (resp. ) denotes the set of non-negative (resp. positive) integers, and we often write for .
- The model—The setting is that of [16]. Let denote a collection of i.i.d. -valued rvs defined on the probability triple , each distributed according to a given (probability) distribution function . With acting as a generic representative for this sequence of i.i.d. rvs, we have
Once F is specified, random thresholds graphs are characterized by two parameters, namely the number n of nodes and a threshold value . The network comprises n nodes, labeled , and to each node k we assign a fitness variable (or weight) For distinct , the nodes k and ℓ are declared to be adjacent if
in which case we say that an undirected link exists between these two nodes. The random threshold graph is the (undirected) random graph defined on the set of vertices with adjacency notion (10).
For each , the degree of node k in is the rv given by
Under the enforced independence assumptions, conditionally on , the rv is a Binomial rv . The rvs being exchangeable, let denote any -valued rv distributed according to their common pmf.
- Existence of a limiting degree distribution—Throughout we make the following assumption on F.
Assumption 1.
There exists a scaling with the property such that
for some non-identically zero mapping.
The mapping is necessarily non-decreasing. The following result overlaps with a similar result by Fujihara et al. [8] (Thm. 2, p. 362).
Proposition 1.
Under Assumption 1, there exists an -valued rv D such that
The rv D is conditionally Poisson (given ξ) with pmf given by
The convergence (13) is equivalent to
If the mapping assumes a constant value , i.e., for all , then the rv D is a Poisson rv with parameter c.
Proof.
Fix , and z in . Standard pre-conditioning arguments yield
under the enforced independence assumptions where we note that
Using (9), we get
Replace by in (16) according to the scaling stipulated in Assumption 1, and let n go to infinity in the resulting equality when . This results in both and , and it is then well known [17] (Prop. 3.1.1., p. 116) that
Invoking the Bounded Convergence Theorem, we obtain
and the desired conclusion (13)–(14) follows as we note that the right-hand side is the probability generating function (pgf) of the pmf (14). □
Assumption 1 holds in a number of interesting cases; in what follows, we use the standard notation for x in . When is exponentially distributed with parameter , namely
Assumption 1 holds with
if we take for all . In this case, the pmf of D is the pmf appearing at (5)–(6); it is given by
as we substitute (18) into the expression (14); note that the rv is exponentially distributed with unit parameter if is exponentially distributed with parameter .
The second case deals with heavy-tailed rvs. The rv is said to be a Pareto rv with parameters and if
Assumption 1 holds with for all , and for all , in which case D is a Poisson rv with unit parameter.
3. The Main Results
Fix and . For each , the rv defined by
counts the number of nodes which have degree d in , while the fraction of nodes with degree d in is given by
The main result of the paper is concerned with the following distributional convergence.
Theorem 1.
Assume Assumption 1 to hold. For each , there exists a non-degenerate -valued rv such that
where the scaling is the one postulated in Assumption 1. Moreover, it holds that and with D being the limiting rv whose existence is established in Proposition 1.
In the course of proving Theorem 1 in Section 5, we determine the distribution of the rv through its characteristic function (36). The non-degeneracy of the rv has the following immediate and important consequence.
Corollary 1.
Assume Assumption 1 to hold. For each , the sequence cannot converge in probability to a constant, i.e., there exists no constant such that
Corollary 1 was announced in the conference paper [11] when the fitness variables are exponentially distributed; in [12] the failure of the convergence (24) was shown, also in the exponential case, with the help of asymptotic results for order statistics. Here, a fuller picture is obtained under the minimal Assumption 1: Corollary 1 is an immediate byproduct of the weak convergence (23) and of the non-degenerate nature of the limiting rv .
The remainder of the paper is concerned with establishing Theorem 1; its proof uses the method of moments, and builds on two technical results, Propositions 2 and 3, which are stated below. Proposition 2 is a multi-dimensional version of Proposition 1, and provides the core technical content behind Theorem 1.
Proposition 2.
Assume Assumption 1 to hold. For each , there exists an -valued rv such that
The limiting rvs are exchangeable, but not independent, each being distributed according to the limiting rv D whose existence is established in Proposition 1.
Proposition 3 stated next relies on the multi-dimensional convergence given in Proposition 2 and provides the convergence result needed to apply the method of moments.
Proposition 3.
Assume Assumption 1 to hold. For each , we have
where the -valued rv is the limiting rv whose existence was established in Proposition 2.
As we are about to embark on establishing these results, we comment on the order of the presentation: Theorem 1 follows readily from Proposition 3 with a short proof given in Section 5. Proposition 3 is an easy byproduct of Proposition 2 and is established next in Section 6. Finally, we turn to proving Proposition 2 which contains the technical contents of the paper; a lengthy multi-step proof is provided in Section 7, Section 8, Section 9 and Section 10.
4. Simulation Results
Before turning to the proofs, we illustrate the difference between the convergence statements (2) and (8) through a limited set of simulation experiments which are discussed in this section. Throughout, the fitness variable is taken to be exponentially distributed with parameter , and the threshold is scaled in accordance with (4), namely for each .
With the number n of nodes given, we generate R mutually independent versions of the random threshold graph ; these realizations are denoted . For each and , let denote the degree of node k in the random graph , and for , let denote the number of nodes with degree d in .
- The rv is non-degenerate—Fix . On the strength of Theorem 1, a natural way to produce an estimate for the probability distribution of the rv is to follow a simple two-step procedure. On the basis of the R i.i.d. realizations of the random threshold graph , a standard estimate of the probability distribution of is provided by the histogram
On the other hand, Theorem 1 states that
where is the set of points of continuity of the probability distribution of . Thus, for each x in , the probability will be well approximated by when n is large (possibly dependent on x).
Combining (27) and (28) with a simple triangle inequality argument naturally leads us to propose the approximation
with integers n and R selected sufficiently large. Put differently, we expect the probability distribution of to be well approximated by the histogram if we select both n and R to be large. If such a histogram were found to be very different from a step function, this would provide compelling evidence that (24) cannot hold, and that the rv is not degenerate.
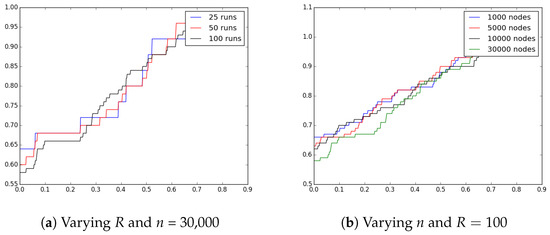
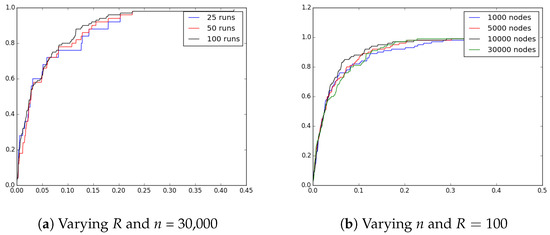
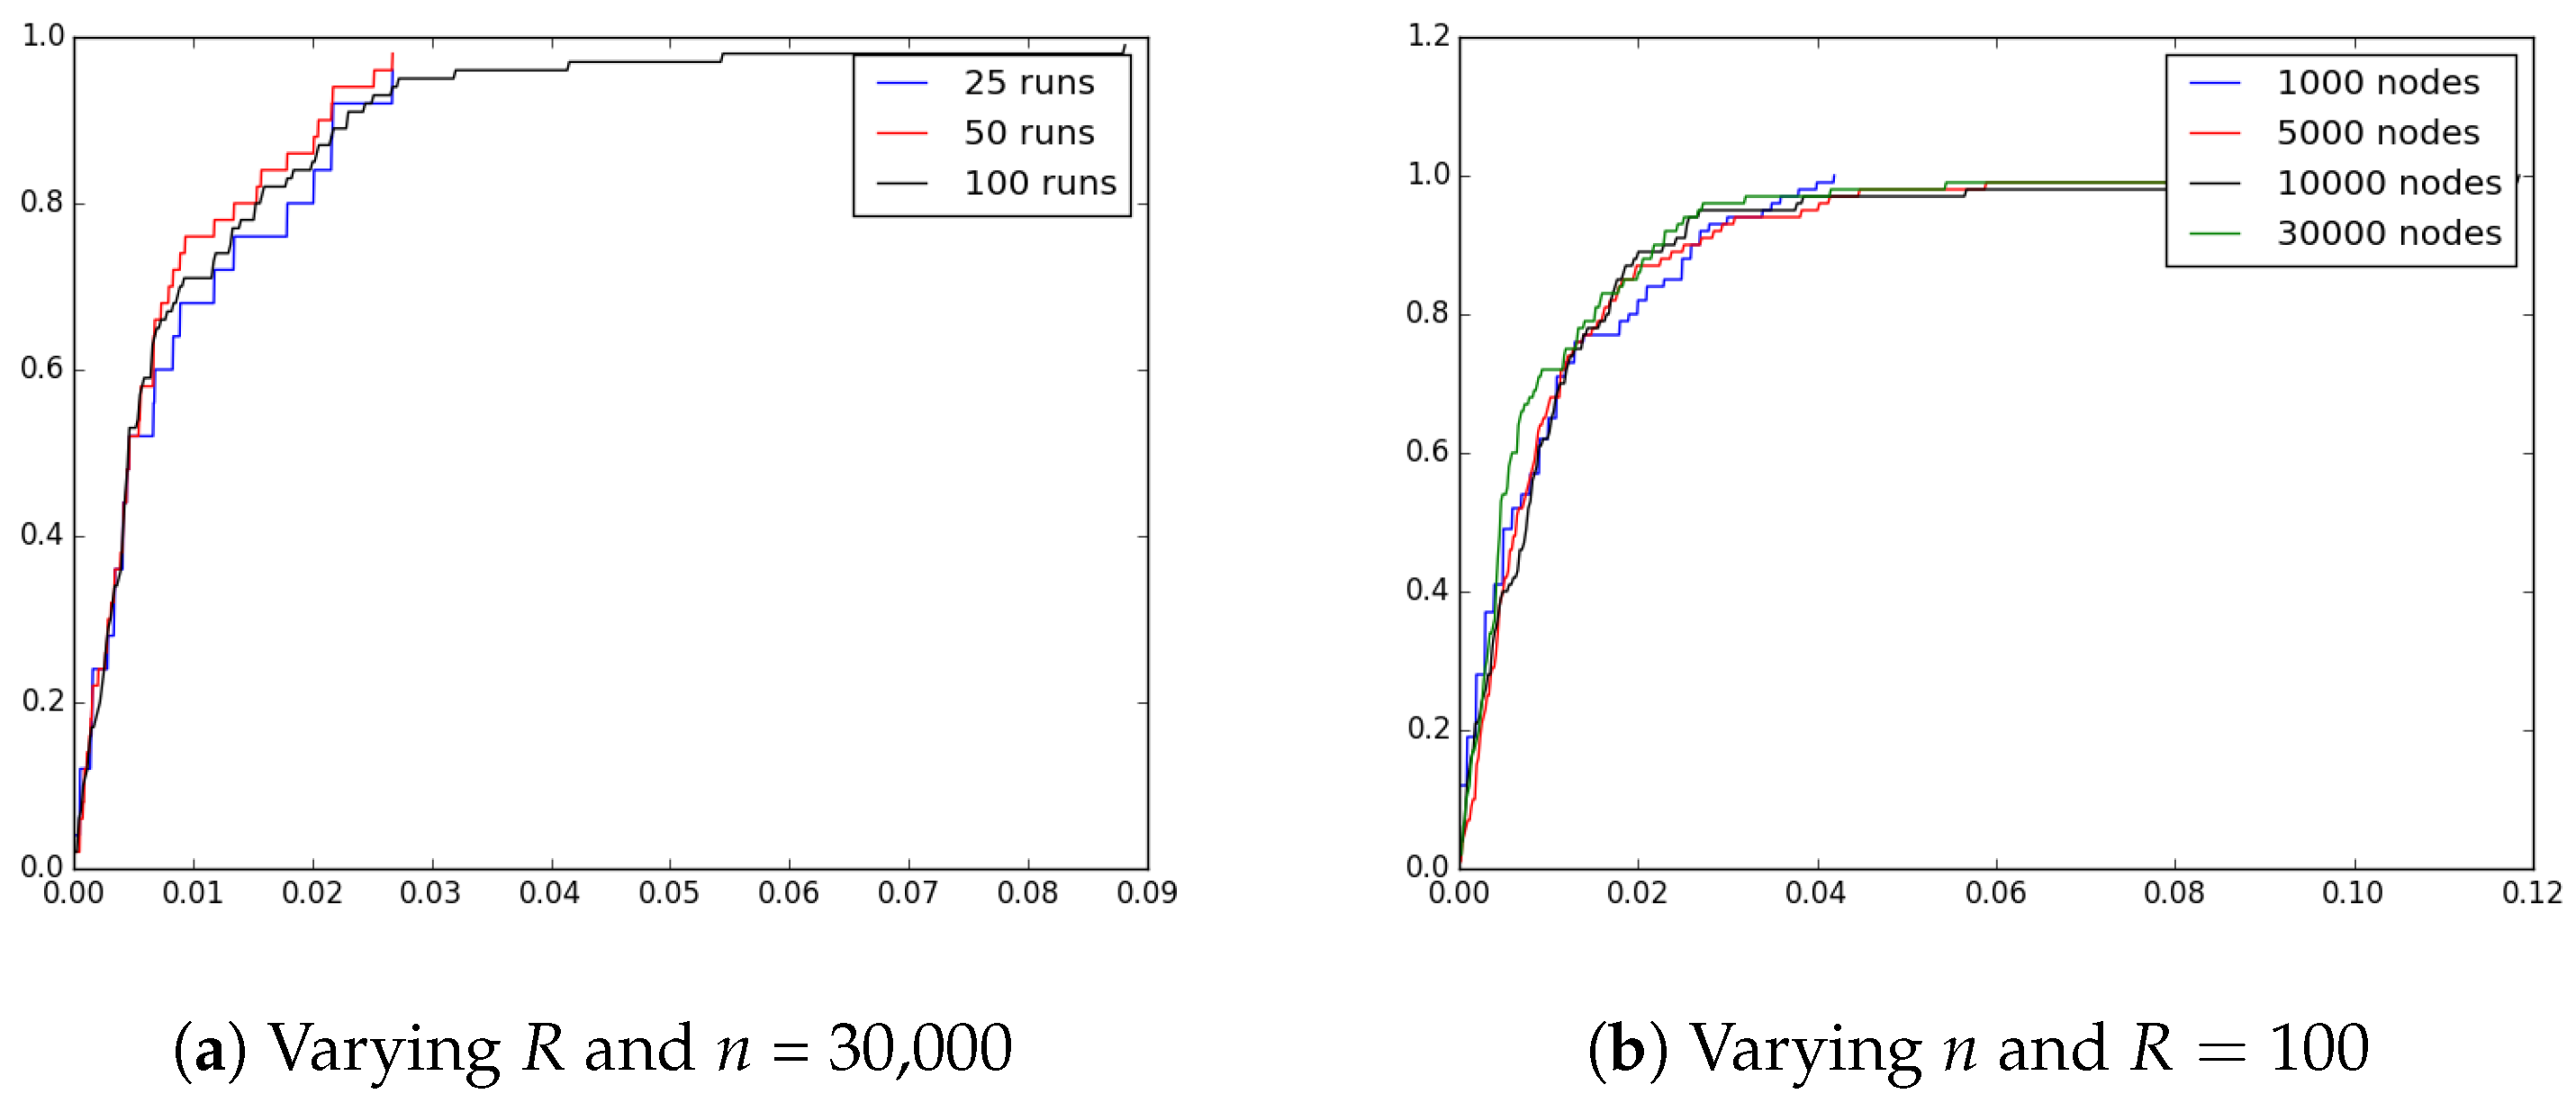
In Figure 1, Figure 2 and Figure 3, we show the approximating histogram for the values , with a varying number R of runs and a varying number n of graph sizes. Figure 1 deals with . Figure 1a shows the histograms for n = 30,000 with increasing values ; the shape of the corresponding histograms do not change significantly. In Figure 1b, with , increasing the graph size n = 1000, 5000,10,000, 30,000 also does not change the histograms significantly. This points to the non-degeneracy of since in all cases the approximating histograms are reasonably close together but never approximate, even remotely, a step function. Figure 2 and Figure 3 exhibit histogram plots for under similar conditions; the conclusions are identical to the ones reached in the case , with the evidence being possibly even stronger since the histograms appear to “bend” in a concave manner.
Figure 1.
Histogram for degree with varying number of nodes n and the number of runs R held fixed, and vice versa.
Figure 2.
Histogram for with varying number of nodes n and the number of runs R held fixed, and vice versa.
Figure 3.
Histogram for with varying number of nodes n and the number of runs R held fixed, and vice versa.
Next, we explore the behavior of the empirical degree distribution (22) along the scaling (4) (with ) as generated through a single network realization. We do so by plotting the histograms
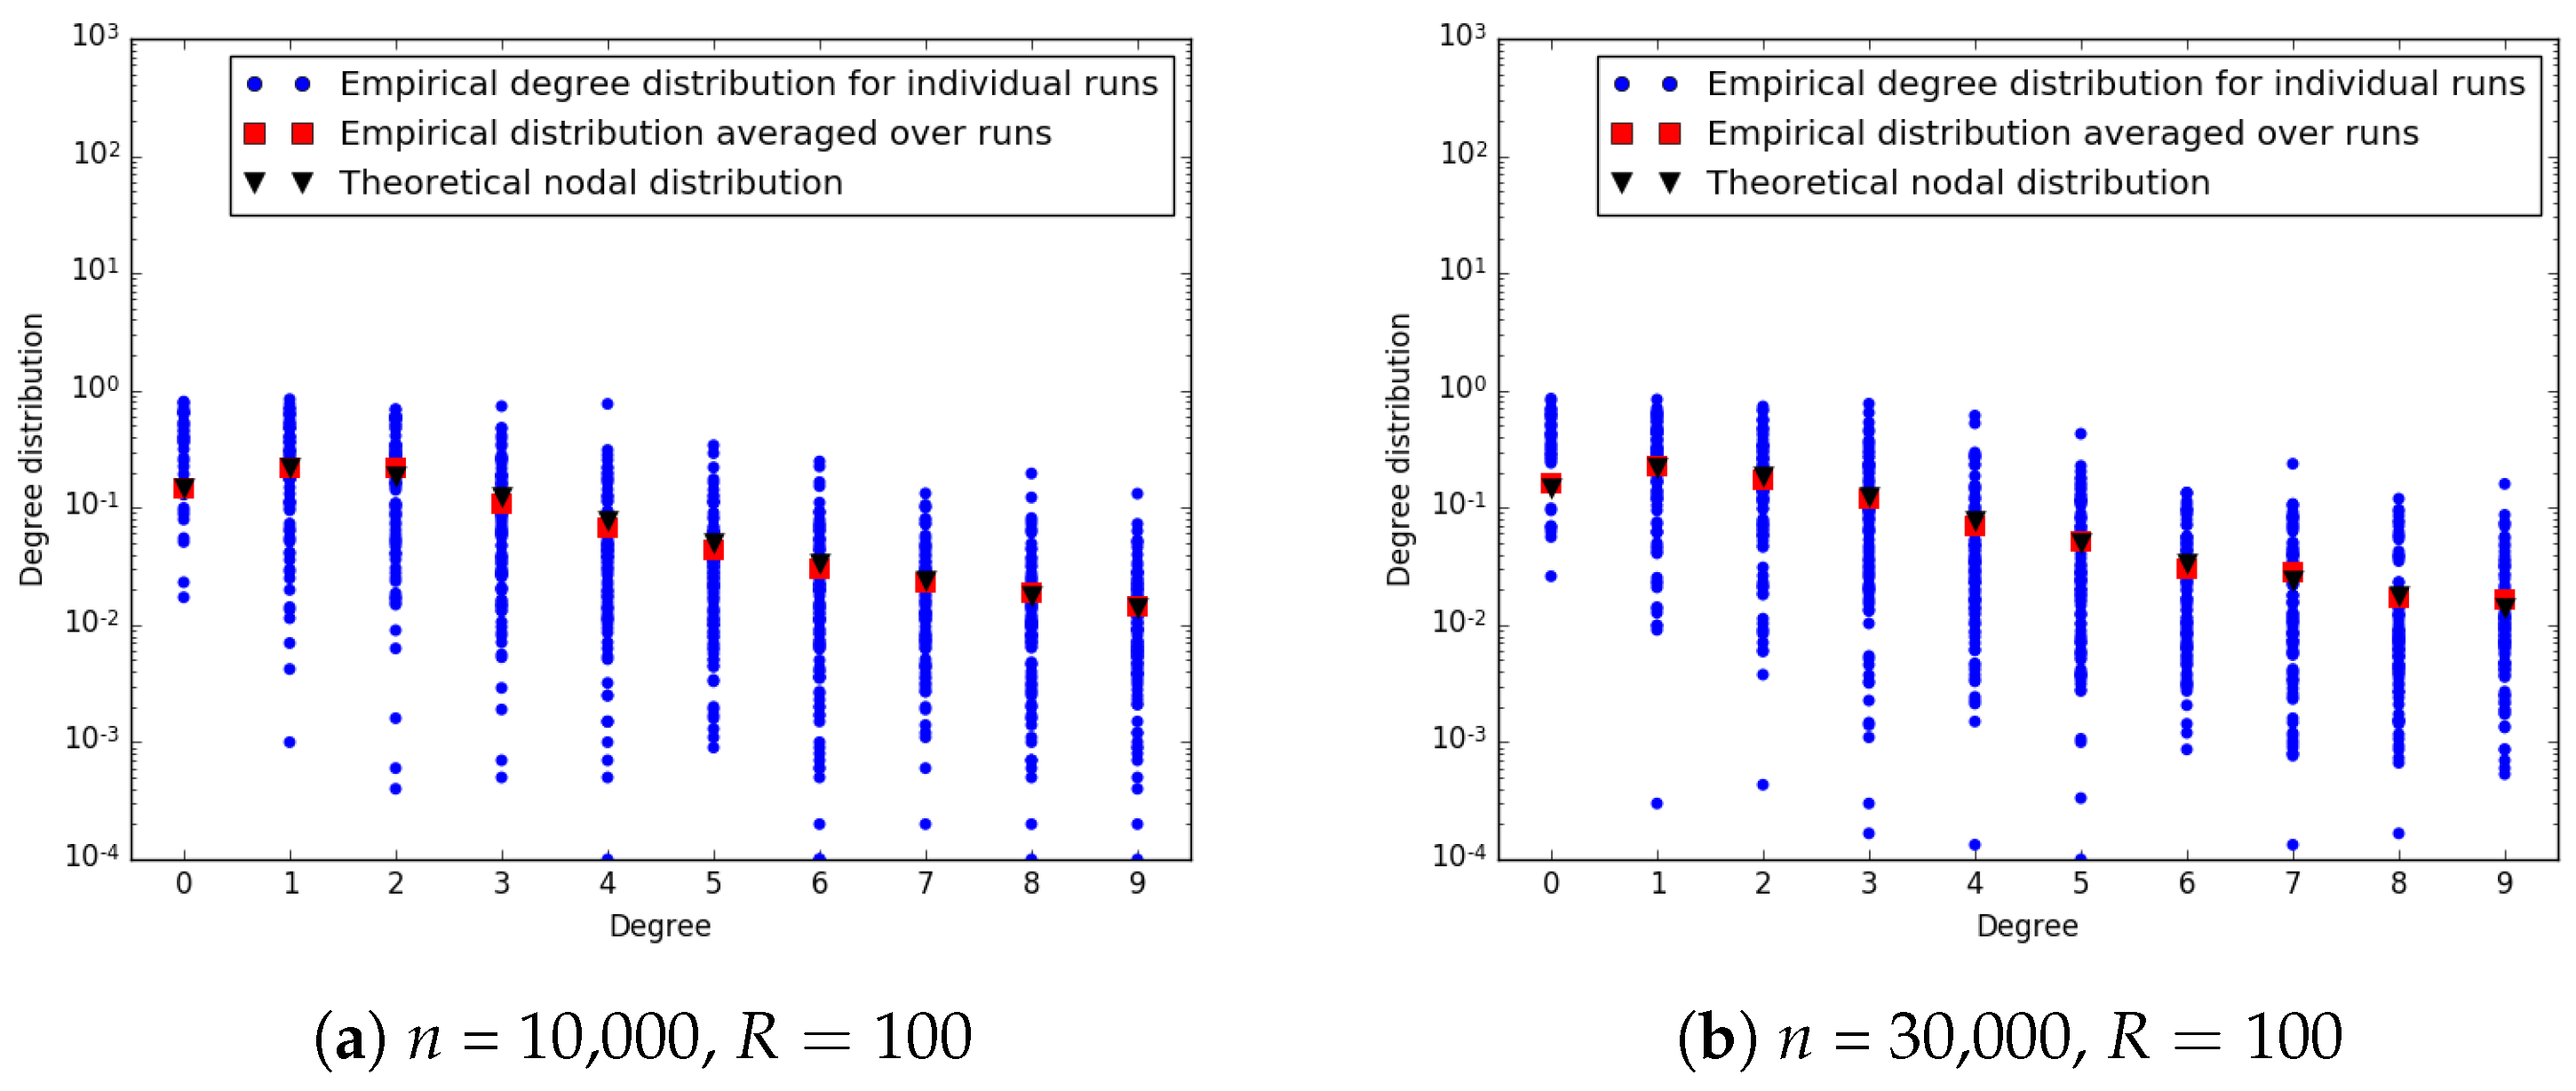
for various values of d and r, and large n, and comparing against the corresponding value for . In Figure 4, we plot the histogram for different runs and varying graph sizes n = 10,000, 30,000, and observe high variability with respect to the nodal degree distribution , which does not change as the graph size is increased.
Figure 4.
The nodal degree distribution was plotted against the empirical degree distribution for various runs .
One might be tempted to smooth out the variability observed in Figure 4 by averaging the empirical degree distributions (31) over the R i.i.d. realizations , resulting in the statistic
Fix . Under these circumstances, the Strong Law of Large Numbers yields
with
by exchangeability. On the other hand, we have by virtue of Proposition 1. Combining these observations yields the approximation
for large n and R. The goodness of the approximation (34) is noted in Figure 4, where the empirical distribution averaged over runs is observed to be very close to the nodal degree distribution. However, the accuracy of the approximation (34) does in no way imply the validity of (7). In fact, the mistaken belief that (7) holds, implicitly assumed in the papers [7,9], might have stemmed from using the smoothed estimate provided by the averaging (34).
5. A Proof of Theorem 1
Fix . We establish the weak convergence of the sequence by arguments based on the method of moments; for details concerning this approach, see the references [14] (Thm. 4.5.5, p. 99) and [18] (Thm. 6.1, p. 140).
Proposition 3 suggests considering the mapping given by
This definition is well posed with always an element of since
In particular, the mapping is analytic on , and hence continuous at . However, at this point in the proof, it is not yet known whether is the characteristic function of a rv.
We close that gap as follows: For each , let denote the characteristic function of the rv , i.e.,
The obvious bound implies the uniform bounds
Therefore, applying the Bounded Convergence Theorem (with R going to infinity), separately to the real and imaginary parts, we readily validate the series expansion
For each t in , it now follows that
Picking a positive integer R, we get
For each , there exists a positive integer (independent of n) such that
and on that range, we obtain
by the usual arguments. Using Proposition 3, we readily conclude that , whence since is arbitrary.
By a standard result due to Cramér and Lévy [14] (Thm. 6.3.2, p. 161) [15] (Thm. 1, p. 320), the mapping , being continuous at with , must be the characteristic function of some rv, say , namely
and the sequence converges weakly to the rv .
6. A Proof of Proposition 3
Fix , and , and pick ; there is no loss of generality in doing so, here and elsewhere, as we are concerned with n large asymptotics. Let denote the collection of all ordered arrangements of r distinct elements drawn from the set . Any such arrangement can be identified with a one-to-one mapping .
We begin with the well-known identity
Taking expectations on both sides of (38), we obtain
by the exchangeability of the rvs . Dividing both sides of (39) by leads to
with .
7. A Proof of Proposition 2
The remainder of the paper is devoted to the proof of Proposition 2. First, some notation: For each , let denote the values of the fitness rvs arranged in increasing order, namely , with a lexicographic tiebreaker when needed. The rvs are known as the order statistics associated with the collection ; in particular, the rvs and are the minimum and maximum of the rvs , respectively [19]. In what follows, the permutation arranges the rvs in increasing order, i.e.,
(under the lexicographic tiebreaker). The permutation being determined by the i.i.d. rvs , it is a random permutation which is uniformly distributed over the group of permutations of . With the notation introduced earlier, write
By convention, the product of an empty set of factors is set to unity in the expression (42) and elsewhere in the discussion below.
Proposition 2 is an easy consequence of the following key analytical result whose proof is broken up in several steps discussed in Section 8, Section 9 and Section 10.
Proposition 4.
Assume Assumption 1 to hold. For each , we have
We devote the remainder of this section to show that Proposition 4 indeed implies Proposition 2.
- Convergence—First, by the Bounded Convergence Theorem, we get
- Exchangeability in the limit—To establish exchangeability, we proceed as follows: For each , the rvs are obviously exchangeable rvs, and the exchangeability of the limiting rvs follows because exchangeability is preserved under the weak convergence (25). This fact could also be gleaned directly from (44) as we note from (42) that the mapping is permutation-invariant in the sense that
As expected, we retrieve Proposition 1 by looking at the case , namely
For , we also find
Comparing (45) and (46), we can check that
and the rvs are therefore not independent. This completes the proof of Proposition 2.
To further illustrate this last point, consider the special case when the mapping appearing in Assumption 1 is constant, say for all , as would be the case for the Pareto distribution (20). The expressions (45) and (46) now become
and
Thus, each of the rvs is Poisson distributed with parameter c and since
Exchangeability yields for every ; hence, , and the rvs are certainly not independent! Moreover, for each , we get for all , whence
In other words, the distribution of the rv is the two-point mass distribution on the set with . Obviously,
since .
When the fitness rv is exponentially distributed, explicit expressions were obtained for by direct arguments in the earlier references [10,11,12]. ■
8. A Proof of Proposition 4—A Reduction Step
Throughout this section, the integer and the parameter are held fixed, and pick . For each , we write
with
As the scaling satisfies , it is plain that
and the desired convergence (43) takes place if and only if
Our first step towards establishing (49) is to evaluate the joint pgfs. Pick in . Under the enforced independence assumptions, it is plain that
9. A Proof of Proposition 4—A Decomposition
Fix and . To further analyze the expression (52) with in , we introduce the set of indices
There are two possibilities which we now explore in turn. Either is empty or it is not, leading to a natural decomposition expressed through Lemmas 1 and 2, respectively.
Lemma 1.
With in , whenever is non-empty, we have
for all in .
Proof.
As an immediate consequence of (55), we have the bounds
on the range (54), since there we have for all .
We now turn to the case when the index set is empty, a fact characterized by the conditions
It will be convenient to arrange the values in increasing order, say , with a lexicographic tiebreaker. Let be any permutation of such that for all . Obviously, this permutation is determined by the values . In what follows, we shall use the convention and .
Lemma 2.
With in , whenever is empty, we have
for all in .
Proof.
In what follows, the values in are held fixed. Given in and , we define the events
Under the enforced conventions, we have and . When is empty, the events are pairwise disjoint and form a partition of the sample space. Using this fact in the expression (51), we find
Three cases need to be considered.
(i) On the event , we have , and thus for all , so that
whence
(ii) With , on the event , we have the inequalities and , whence
We readily conclude that
(iii) Finally, on the event , we have , and thus for all , so that
whence
10. A Proof of Proposition 4—Taking the Limit
In order to establish the convergence (49), we return to the expression (52) for the joint pgf of the relevant rvs.
- A useful intermediary fact—Pick and fix with . For arbitrary , consider in and in . In what follows, it will be convenient to define
Whenever is empty, Lemma 2 gives
Replace by in () according to the scaling stipulated in Assumption 1. Letting n go to infinity in the resulting relation, we get
and
As a result, with empty, we have
and the conclusion
follows by standard arguments [17] (Prop. 3.1.1., p. 116). ■
- In the limit—Pick scalars in the range (54). For each with , we start with the decomposition
Next, for each such that , we also have
with (63) yielding
As we pass from (63) to (70), we recall that the order statistics associated with were introduced in the statement of Proposition 4, together with the random permutation . The random permutation coincides with the deterministic permutation induced by the values with .
Author Contributions
Conceptualization, A.M.M.; Methodology, A.M.M. and S.P.; Software, S.P.; Validation, A.M.M. and S.P.; Formal analysis, A.M.M. and S.P.; Investigation, A.M.M. and S.P.; Writing—original draft, A.M.M. and S.P.; Writing—review & editing, A.M.M. and S.P.; Visualization, S.P.; Supervision, A.M.M.; Funding acquisition, A.M.M. All authors have read and agreed to the published version of the manuscript.
Funding
This work was supported by NSF Grant CCF-1217997 and by a fellowship from the Lady Davis Trust.
Data Availability Statement
The original contributions presented in this study are included in the article. Further inquiries can be directed to the corresponding author.
Acknowledgments
The paper was completed during the academic year 2014–2015 while Armand M. Makowski was with the Department of Statistics of the Hebrew University of Jerusalem (Israel) with the support of a fellowship from the Lady Davis Trust. During that period, Siddharth Pal was with the Department of Electrical and Computer Engineering and the Institute for Systems Research, University of Maryland, College Park, MD 20742, USA. He is now with RTX BBN Technologies. This document does not contain technology or technical data controlled under either the U.S. International Traffic in Arms Regulations or the U.S. Export Administration Regulations.
Conflicts of Interest
Siddharth Pal is presently employed by the company RTX BBN Technologies. Armand M. Makowski declares that the research was conducted in the absence of any commercial or financial relationships that could be construed as a potential conflict of interest.
References
- Durrett, R. Random Graph Dynamics; Cambridge Series in Statistical and Probabilistic Mathematics; Cambridge University Press: Cambridge, UK, 2007. [Google Scholar]
- Barabási, A.-L.; Albert, R. Emergence of scaling in random networks. Science 1999, 286, 509–512. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Newman, M.E.J. The structure and function of complex networks. SIAM Rev. 2003, 45, 167–256. [Google Scholar] [CrossRef] [Scilit]
- Clauset, A.; Rohilla Shalizi, C.; Newman, M.E.J. Power-law distributions in empirical data. SIAM Rev. 2009, 51, 661–703. [Google Scholar] [CrossRef] [Scilit]
- Voitalov, I.; van der Hoorn, P.; van der Hofstad, R.; Krioukov, D. Scale-free well done. Phys. Rev. Res. 2019, 1, 033034. [Google Scholar] [CrossRef] [Scilit]
- Bollobás, B.; Riordan, O.; Spencer, J.; Tusnády, G. The degree sequence of a scale free random graph process. Random Struct. Algorithms 2001, 18, 279–290. [Google Scholar] [CrossRef] [Scilit]
- Caldarelli, G.; Capocci, A.; De Los Rios, P.; Muñoz, M.A. Scale-free networks from varying vertex intrinsic fitness. Phys. Rev. Lett. 2002, 89, 258702. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Fujihara, A.; Ide, Y.; Konno, N.; Masuda, N.; Miwa, H.; Uchida, M. Limit theorems for the average distance and the degree distribution of the threshold network model. Interdiscip. Inf. Sci. 2003, 15, 361–366. [Google Scholar] [CrossRef] [Scilit]
- Servedio, V.D.P.; Caldarelli, G. Vertex intrinsic fitness: How to produce arbitrary scale-free networks. Phys. Rev. E 2004, 70, 056126. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Pal, S. Adventures on Networks: Degrees and Games. Ph.D. Thesis, Department of Electrical and Computer Engineering, University of Maryland, College Park, MD, USA, 2015. [Google Scholar]
- Pal, S.; Makowski, A.M. On the asymptotics of degree distributions. In 2015 54th IEEE Conference on Decision and Control (CDC), Osaka, Japan, 15–18 December 2015; IEEE: Piscataway, NJ, USA, 2015. [Google Scholar]
- Pal, S.; Makowski, A.M. Asymptotic distributions in large (homogeneous) random networks: A little theory and a counterexample. IEEE Trans. Netw. Sci. Eng. 2019, 7, 1531–1544. [Google Scholar] [CrossRef] [Scilit]
- Billingsley, P. Convergence of Probability Measures; John Wiley & Sons: New York, NY, USA, 1968. [Google Scholar]
- Chung, K.L. A Course in Probability Theory, 2nd ed.; Academic Press: New York, NY, USA, 1974. [Google Scholar]
- Shiryayev, A.N. Probability; Boas, R.P., Translator; Graduate Texts in Mathematics; Springer: New York, NY, USA, 1984; Volume 95. [Google Scholar]
- Makowski, A.M.; Yağan, O. Scaling laws for connectivity in random threshold graph models with non-negative fitness variables. IEEE J. Sel. Areas Commun. 2013, 31, 573–583. [Google Scholar] [CrossRef] [Scilit]
- Embrechts, P.; Klüppelberg, C.; Mikosch, T. Modelling Extremal Events for Insurance and Finance; Springer: Berlin/Heidelberg, Germany, 1997. [Google Scholar]
- Janson, S.; Łuczak, T.; Ruciński, A. Random Graphs; Wiley-Interscience Series in Discrete Mathematics and Optimization; John Wiley & Sons: New York, NY, USA, 2000. [Google Scholar]
- David, H.A.; Nagaraja, H.N. Order Statistics, 3rd ed.; Wiley Series in Probability and Statistics; John Wiley & Sons: Hoboken, NJ, USA, 2003. [Google Scholar]
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.