


Abstract
Multimodal sentiment analysis integrates text, audio, and visual signals to infer affective states. However, sentiment information shared across modalities is often entangled with modality-specific variation, and existing representation learning methods do not fully exploit the relations encoded by continuous sentiment labels. Effective cross-view alignment therefore requires structured representations and a target that captures affective relations among samples. We propose a label-aware distributional contrastive alignment framework to address these requirements. Shared-private representation learning separates common sentiment information from modality-specific cues. The shared representations form audio–text and visual–text interaction views guided by a common textual reference, while the private representations retain complementary cues for prediction. Label-Aware GCA-UOT aligns the two sets of interaction views through batch-level distributional matching. Entropic unbalanced optimal transport provides a smooth, flexible coupling, and a label-aware target guides the allocation of matching mass according to paired-view correspondence, sentiment-intensity proximity, and polarity consistency. Experiments on CMU-MOSI, CMU-MOSEI, and CH-SIMS show consistent gains in fine-grained sentiment classification. Our method improves Acc-5 by 0.5–2.9 percentage points over the strongest baseline on each dataset and achieves the best or joint-best Acc-7 among the compared methods on CMU-MOSI and CMU-MOSEI.
1. Introduction
Multimodal sentiment analysis (MSA) aims to infer human affective states from text, audio, and visual signals. Compared with text-only analysis, MSA can use complementary cues from verbal content, acoustic prosody, and visual behavior. Benchmarks such as CMU-MOSI, CMU-MOSEI, and CH-SIMS have supported research on fine-grained sentiment prediction in English and Chinese [1,2,3,4]. Effective MSA remains challenging because modalities differ in their distributions, temporal structures, and semantic content. Text often expresses sentiment explicitly, whereas audio and visual signals can be noisier and more dependent on context. Sentiment annotations also commonly take the form of continuous scores with an ordinal interpretation. Utterances with similar scores may therefore share affective information that is lost when samples are treated independently or assigned only to discrete categories.
Existing studies address these challenges in several ways. Fusion methods model cross-modal interactions through tensor fusion, low-rank fusion, attention, or language-model adaptation [5,6,7,8]. Representation learning methods separate information shared across modalities from modality-specific information [9,10,11,12]. Text-guided methods use textual semantics to refine non-text representations and support cross-modal interaction [13,14,15,16]. These approaches improve how multimodal features are constructed and combined. Continuous sentiment prediction also requires attention to how the resulting representations are aligned with the sentiment relations among samples.
Contrastive learning organizes representation spaces by imposing relational constraints among samples or views, typically encouraging related representations to remain close while separating unrelated ones [17,18]. In MSA, contrastive objectives have been employed to improve cross-modal consistency, decompose shared and modality-specific information, and exploit sentiment-aware sample relations [12,19,20]. Despite their different relation definitions, these objectives generally express relational supervision through pairwise similarities among individual samples or views. Such pairwise formulations provide effective local constraints, but they do not explicitly represent the joint matching structure between two sets of cross-view representations.
Optimal transport (OT) addresses representation alignment at the distribution level by learning a global matching plan between two representation sets [21,22]. Entropy regularization produces smooth transport plans that can be computed efficiently with Sinkhorn-type methods [23,24,25]. Unbalanced OT further relaxes strict marginal constraints to accommodate noisy or partial correspondences [26]. GCA-UOT applies this formulation to contrastive representation learning, treating cross-view alignment as transport-plan learning [27]. Its paired-instance target specifies correspondence between two views of the same utterance but does not distinguish non-paired utterances according to their sentiment labels. This distinction matters in MSA: utterances with similar sentiment intensities may be more closely related than those with substantially different scores. Although entropic UOT can allocate mass to off-diagonal entries, this flexibility alone does not identify affectively meaningful neighbors. We therefore investigate whether incorporating continuous-label relations into the target transport distribution improves the organization of cross-view representations for fine-grained sentiment prediction.
We combine shared-private representation learning, text-guided interaction, and GCA-UOT in a framework for fine-grained multimodal sentiment prediction. Shared representations form audio–text and visual–text interaction views guided by a common textual reference, while private representations retain complementary modality-specific cues. Our methodological extension, Label-Aware GCA-UOT (LA-GCA-UOT), uses a target transport distribution derived from continuous labels to supervise alignment between the interaction views. The target combines paired-view correspondence, soft neighborhood relations based on label distance, and polarity consistency. It thus specifies the desired sentiment relations within the batch-level matching structure. The interaction and private representations are then fused for prediction.
The main contributions of this work are summarized as follows:
- We present a representation-and-alignment framework for fine-grained multimodal sentiment prediction, using shared-private representations and text-guided interaction to construct the views for LA-GCA-UOT. The framework provides the representation setting for the proposed alignment target and retains private modality cues for final prediction.
- Within this framework, we extend GCA-UOT with a continuous-label target transport distribution. Paired correspondence, sentiment-distance weighting, and polarity consistency jointly specify the desired matching structure between the interaction views.
- Experiments on CMU-MOSI, CMU-MOSEI, and CH-SIMS evaluate the framework and its design choices through external-model comparisons, structural and component ablations, and sensitivity analysis. Same-backbone objective comparisons on the English benchmarks further examine the alignment formulation. The results demonstrate consistent gains in fine-grained sentiment classification across all three benchmarks.
2. Related Work
2.1. Multimodal Sentiment Analysis
The development of contextual text representations also provides a foundation for sentiment modeling. SiAraSent compares engineered lexical and emoji features with AraBERT-based representations and fine-tuning for Arabic text sentiment analysis [28], illustrating the progression from feature engineering to contextual Transformer representations. Multimodal sentiment analysis extends this representation-learning setting by incorporating acoustic and visual information.
Effective multimodal sentiment analysis requires fusion mechanisms that integrate heterogeneous text, audio, and visual signals. Research has progressed from static fusion to explicit cross-modal interaction and refinement of the fusion process. Early methods used feature concatenation, tensor composition, or low-rank approximation to preserve joint multimodal information. Later methods introduced attention, gating, and Transformers to model dynamic dependencies across modalities. More recent approaches emphasize information preservation, representation regularization, and text-guided interaction to improve the stability and discriminative quality of fused representations [5,6,7,8,15,16,29].
Several methods illustrate this progression. TFN models joint multimodal features through tensor fusion, while LMF provides an efficient low-rank approximation [5,6]. MulT uses directional cross-modal attention to capture long-range dependencies in unaligned sequences [7]. MAG-BERT incorporates audio and visual information into pretrained language models through adaptation gates [8]. MMIM emphasizes information preservation by hierarchically maximizing mutual information between unimodal inputs and fused representations [29]. Recent text-guided methods use textual semantics to refine non-text representations, exploiting text as a reference for cross-modal sentiment interaction [15,16]. Alongside these advances in fusion, another line of research examines the internal organization of multimodal representations.
Modalities differ in how they express information, in their granularity, and in their semantic content. Fusion architecture alone therefore cannot guarantee robust, discriminative representations. Multimodal representation learning addresses this issue through three broad strategies. First, translation, cross-modal interaction, and contextual modeling reduce semantic gaps and facilitate alignment in a shared space [30,31]. Second, auxiliary tasks, self-supervised learning, and knowledge enhancement provide additional training signals to improve generalization and training stability [32]. Third, structured constraints such as shared-private decomposition separate common information from modality-specific variation, reducing entanglement and improving interpretability [9,33].
Recent work also extends disentangled representation learning to incomplete multimodal inputs. Li et al. propose DERL, which combines hybrid experts for shared/private disentanglement, multi-level collaborative reconstruction, and importance-aware fusion to address missing modalities [34]. This work highlights the role of representation decomposition in recovering useful information under incomplete observations. Whereas DERL emphasizes representation recovery under missing modalities, our framework uses continuous sentiment labels to organize the distributional alignment of shared interaction views.
These strategies share a central goal: constructing representations that capture common information while preserving differences across modalities. They can reduce semantic discrepancies and improve sentiment prediction, but they focus mainly on representation construction and fusion. Less attention has been given to assigning the resulting representations distinct roles in distributional alignment. In our framework, shared representations are refined into audio–text and visual–text interaction views for LA-GCA-UOT, while private representations pass directly to the final predictor. This design connects structured representation learning with alignment while preserving modality-specific information outside the shared alignment space.
2.2. Contrastive Learning
Contrastive learning brings related samples or views closer in representation space and separates unrelated ones. It has been widely studied in both self-supervised and supervised settings [17,18]. In MSA, Lin and Hu combine unimodal encoding with cross-modal prediction to improve representation consistency and robustness [35]. Lin et al. use hierarchical graphs to capture intra-modal and inter-modal relations beyond whole-utterance representations [36]. ConFEDE combines contrastive learning with feature decomposition to organize shared and modality-specific information [12]. CLGSI uses sentiment-intensity differences to select and weight positive and negative pairs, providing finer relational supervision than fixed binary assignments [20].
Beyond sentiment analysis, CodeLLM-Auth combines code stylometry with pretrained code-Transformer representations through cross-attention fusion and supervised contrastive learning for source-code authorship attribution and verification [37]. This application illustrates the use of supervised contrastive objectives to organize complementary representations around author identity, whereas sentiment-aware objectives organize relations according to affective labels.
These studies show how labels can refine contrastive supervision. Their constraints, however, are primarily expressed through pairwise or anchor-wise comparisons. They adjust individual relations without explicitly optimizing a joint matching structure between two representation sets. This distinction matters for continuous sentiment prediction, where relations between non-paired views can carry different degrees of affective relevance.
We therefore use continuous labels to construct a batch-level target transport distribution. The target retains paired correspondence while using sentiment-intensity proximity and polarity consistency to define relations between non-paired views. This integrates label-aware supervision directly into distributional contrastive alignment.
2.3. Optimal Transport
Optimal transport (OT) learns a joint coupling between empirical distributions and has been increasingly applied to alleviate modality heterogeneity in multimodal sentiment analysis [21]. InfoEnh employs OT-enhanced domain adaptation to map heterogeneous modalities into a common feature space [38]. AlignMamba uses an OT-based local alignment module to establish token-level cross-modal correspondences before multimodal interaction [39], while PaSE applies entropic OT to improve the semantic consistency of calibrated unimodal representations before fusion [40]. These studies demonstrate the effectiveness of transport-based modeling for multimodal representation alignment. However, their transport objectives mainly organize feature-, token-, or prototype-level correspondences and are not designed to represent graded sentiment relations between two cross-view representation sets.
Parallel to these developments, sentiment-aware contrastive methods have incorporated label distance, sentiment intensity, or polarity information into positive-pair selection and pairwise weighting [20]. Compared with fixed binary positive–negative assignments, such supervision provides a finer description of inter-sample sentiment relations. Nevertheless, these relations are still primarily imposed on individual sample pairs and therefore do not directly determine the joint matching structure between two sets of cross- view representations.
OT has also been connected with contrastive representation learning. Generalized Contrastive Alignment (GCA) provides a transport-plan-based formulation in which cross-view relations are jointly represented through a coupling, rather than being optimized only as independent pairwise similarities [27]. This perspective extends contrastive learning from isolated positive–negative relations to the relational structure between two representation sets. However, the target used in the standard paired-view setting remains primarily determined by instance correspondence, while continuous sentiment intensity and polarity have not been incorporated into the target transport structure for multimodal sentiment analysis.
These lines of research address related but distinct aspects of alignment. OT-based MSA methods mainly reduce feature-level discrepancies, sentiment-aware contrastive methods encode continuous labels through pairwise constraints, and transport-based contrastive methods largely use paired-instance targets. Our method connects these ideas by using continuous sentiment relations to define a target coupling between audio–text and visual–text interaction representations. The target combines paired correspondence, sentiment-intensity proximity, and polarity consistency, extending label supervision to the joint alignment of two representation sets.
3. Materials and Methods
Figure 1 shows the four stages of the proposed framework: input projection, decoupled text-guided encoding, label-aware distributional contrastive alignment, and fusion for prediction. First, modality-specific projections map text, audio, and visual inputs into a common latent space. Shared and private encoders then separate the information used for cross-modal interaction from modality-specific cues retained for prediction. TGCE constructs audio–text and visual–text interaction views from the shared representations using a common textual reference. LA-GCA-UOT aligns these views with a target distribution that encodes paired correspondence and cross-sample sentiment relations. Finally, the interaction and private representations are concatenated for sentiment prediction.
Figure 1.
Overall framework of the proposed method.
3.1. Task Formulation
We consider the standard multimodal sentiment analysis setting, where each utterance consists of three modalities: text, audio, and visual signals. Given a preprocessed utterance, the unimodal input sequences are denoted as , , and , where and denote the sequence length and feature dimension of modality , respectively.
Because the input feature dimensions and representation spaces differ across modalities, we use modality-specific projections to map each input sequence into a common latent space:
where denotes the projection function for modality m, and d is the unified latent feature dimension. For notational simplicity, , , and are used throughout the following sections to denote the projected text, audio, and visual representations, respectively.
The goal of multimodal sentiment analysis is to predict the sentiment label or sentiment intensity score y from the multimodal representations:
where denotes the proposed multimodal sentiment prediction model, and is the predicted sentiment output.
3.2. Decoupled Text-Guided Representation Learning
Cross-modal interaction benefits from representations that emphasize modality-consistent sentiment semantics while preserving modality-specific complementary cues. Inspired by shared-private representation learning in multimodal sentiment analysis [9,41], we first decompose each modality into shared and private representations. The shared representations provide a semantic basis for cross-modal interaction, while the private representations retain complementary modality-specific evidence for final prediction.
Given the projected modality representation , we employ a shared encoder and modality-specific private encoders to obtain the sequence-level shared and private representations:
where . Here, denotes the shared encoder and denotes the private encoder for modality m. The shared representation provides a sequence-level semantic basis for subsequent text-guided cross-modal refinement, whereas the private representation preserves sequence-level modality-specific complementary cues.
To reduce redundant correlations between the shared and private representations, we employ an orthogonality-based decoupling constraint. For modality m, let and denote the normalized shared and private feature vectors of the b-th sample at the i-th temporal position, respectively. The decoupling loss is defined as
where , and B is the batch size. This constraint reduces overlap between the shared and private representations within each modality. The shared representations support text-guided interaction, while the private representations retain complementary modality-specific information for prediction. LA-GCA-UOT subsequently organizes cross-view sentiment relations after text-guided refinement.
Text often provides explicit sentiment information and stable contextual cues in multimodal sentiment analysis [41,42,43]. We therefore use it to guide cross-modal interaction and establish a common semantic reference for label-aware alignment. Following the directional cross-modal attention formulation in MulT [7], we use a Text-guided Cross-modal Encoder (TGCE) to refine the shared audio and visual representations. For each non-text modality , the shared representation supplies the queries, and the shared text representation supplies the keys and values. The resulting interaction representation is
where denotes the TGCE for modality m. It combines text-guided cross-modal attention with self-attention refinement, using , , and . This produces the audio–text representation and the visual–text representation . Both views originate from shared representations and are refined using the same textual reference, providing a common semantic basis for label-aware transport alignment. They are used for both alignment and prediction; the private representations supply additional modality-specific cues to the final predictor.
3.3. Label-Aware Distributional Contrastive Alignment
Conventional contrastive learning typically aligns views through instance correspondence: the paired view of an anchor is positive, and other views receive discrete positive or negative assignments [17,18]. Such objectives have been used in MSA to reduce modality gaps and improve cross-modal consistency [12,15,19]. Continuous sentiment scores provide a richer relation between utterances. Two utterances with similar intensities may offer useful mutual supervision even when they are not views of the same instance.
Following generalized contrastive alignment, we formulate cross-view contrastive learning as distributional alignment [27]. The model infers a transport-based alignment distribution from the current representations and trains it to approach a target distribution encoding the desired matching structure. Vanilla GCA-UOT primarily uses paired-view identity to define this target. LA-GCA-UOT extends the target with soft neighborhood relations based on sentiment-label distance and a mask enforcing negative/non-negative polarity consistency. The objective thus preserves paired correspondence while incorporating the graded relations encoded by continuous sentiment labels.
3.3.1. Cross-View Transport Formulation
Each utterance has two sentiment-oriented interaction views: the audio–text representation and the visual–text representation . For a mini-batch of B samples, the two representation sets are
We treat and as two cross-view supports and formulate their alignment as a transport problem. Under this formulation, the diagonal relation corresponds to the paired audio–text and visual–text representations from the same utterance, while the off-diagonal relation corresponds to cross-view relations between different utterances in the same mini-batch.
After normalization, the cross-view transport costs are computed by cosine dissimilarity:
where and denote normalized interaction representations. Let denote one alignment direction. Given the cost matrix , the transport plan is estimated by an entropic unbalanced optimal transport objective:
where is the transport-plan variable, is the entropy regularization coefficient, and are uniform reference marginals, and and control the strength of marginal relaxation. Each entry represents the amount of matching mass transported from the i-th source-view representation to the j-th target-view representation. The unbalanced formulation relaxes strict marginal matching, making the learned transport plan more tolerant of noisy or weak cross-view correspondences.
The alignment loss compares the matching distributions for each source representation, so we normalize the transport plan row by row:
where is a small constant for numerical stability. The resulting represents the learned row-wise cross-view alignment distribution inferred from the current interaction representations.
3.3.2. Label-Aware Target Transport Distribution
The learned distribution is inferred from representation similarities through unbalanced OT. By contrast, the target distribution is constructed from sentiment labels and specifies the matching structure that the learned distribution should approach.
The paired-view correspondence is defined by the following identity relation:
This term preserves the reliable instance-level correspondence between and . To further encode continuous sentiment relations, we define a negative/non-negative polarity mask:
where neutral samples are grouped with non-negative samples in the current implementation. This mask prevents utterances with opposite sentiment orientations from being assigned overly large soft matching weights merely because their sentiment scores are numerically close.
Combining paired-view correspondence, label-distance affinity, and the polarity mask gives the unnormalized target relation matrix:
where controls the weight of paired correspondence, controls the contribution of soft label-aware relations, and sets the scale of the decay with label distance. The first term assigns a dedicated weight to paired views. The second assigns soft matching mass to non-paired samples with similar sentiment intensities and the same negative/non-negative polarity. The target therefore captures local sentiment neighborhoods in addition to one-to-one instance correspondence.
The normalized label-aware target transport distribution is obtained by row normalization:
This target distribution converts continuous and ordinal sentiment supervision into a cross-view distributional matching structure.
Variational Justification
The construction in Equation (12) admits an exact variational interpretation under three modeling assumptions: absolute label difference measures sentiment discrepancy; non-paired relations are admissible only within the same negative/non-negative group; and paired correspondence receives a distinct prior weight. Together, these assumptions encode sentiment proximity, polarity consistency, and paired-view correspondence in the target. The derivation below uses the ideal normalization with ; the implemented expression includes a small numerical stabilizer.
For anchor i, define the admissible set
For , assign a reference distribution on this set by
The reference distinguishes the known paired correspondence from other admissible candidates, while treating those candidates equally before their label distances are considered. Minimizing the expected absolute label distance favors samples with similar sentiment scores. KL regularization penalizes deviations from the reference distribution, preserving its distinction between paired and non-paired candidates.
Proposition 1
(Label-aware target as a unique variational solution). Let denote the probability simplex supported on . The unique minimizer of
is , with zero mass outside .
Proof.
Set and . Direct substitution gives
The KL divergence is non-negative and vanishes only at , proving uniqueness. Substituting the reference weights and using yields precisely the normalized relation in Equation (12). □
Thus, absolute label distance with KL regularization yields the exponential affinity, the polarity mask specifies its support, and avoids double counting the paired prior. The proposition provides a variational basis for the target under the stated modeling assumptions.
Parameter Interpretation and Boundary Cases
Writing , the ideal target satisfies
For a fixed , the ideal normalized target depends on and only through their ratio . If , the paired entry exceeds every individual off-diagonal entry, but it need not contain a majority of the total mass because neighborhood size also matters. The parameter controls distance selectivity relative to the label scale: smaller values suppress positive-distance neighbors more strongly, while identical-label neighbors retain their prior weight. Setting , or having no admissible neighbor, recovers the paired-only target.
The resulting row-wise target supervises the representation-based UOT coupling, whose entries are learned jointly across the batch under the full training objective.
3.3.3. LA-GCA-UOT Objective
The LA-GCA-UOT objective optimizes the learned cross-view transport distributions toward the label-aware target distribution. We first define the row-normalized paired-view target as
Since is an identity matrix in the cross-view formulation, provides a strict instance-level anchor between the paired audio–text and visual–text interaction representations.
For each direction , we define the paired-view alignment term and the label-aware soft alignment term as
The paired-view term stabilizes instance-level cross-view correspondence, while the soft alignment term encourages the learned transport distribution to follow the sentiment-label-aware matching structure. The final LA-GCA-UOT loss is computed by averaging the two alignment directions:
where and balance the strict paired-view alignment and the label-aware soft distributional alignment. Through this objective, LA-GCA-UOT extends rigid paired-view contrastive learning into a label-aware distributional alignment problem over text-guided interaction representations.
3.4. Prediction and Training Objective
For sentiment prediction, the model combines the text-guided interaction representations with the private representations. Temporal pooling first converts the private representation sequences into utterance-level vectors:
where denotes the temporal aggregation operation.
For the i-th sample, the final fused representation and prediction are defined as
where and denote the visual–text and audio–text interaction representations, respectively, and , , and denote the temporally aggregated private representations.
We use an regression loss for continuous sentiment prediction. Auxiliary supervision on the audio and visual private branches encourages them to retain complementary modality-specific sentiment cues:
where and are modality-specific auxiliary prediction heads, and follows the same regression loss form as . The text private representation is directly involved in the final fusion and is optimized through the main prediction objective.
The overall training objective combines sentiment prediction, private supervision, shared-private decoupling, and label-aware distributional contrastive alignment:
where , , and are trade-off hyperparameters. The decoupling loss regularizes the separation between shared and private representations, while the LA-GCA-UOT loss promotes label-aware distributional alignment between the audio–text and visual–text interaction representations.
4. Experiments
4.1. Experimental Setup
4.1.1. Datasets
We evaluate the method on three widely used MSA benchmarks: CMU-MOSI [1], CMU-MOSEI [2], and CH-SIMS [3]. CMU-MOSI contains English utterances from online opinion videos, annotated with sentiment scores from to . CMU-MOSEI uses a similar annotation scheme and provides a substantially larger, more diverse collection of English utterances. CH-SIMS contains Chinese utterances with fine-grained sentiment scores from to , enabling evaluation in a different language. Every sample includes text, audio, and visual inputs. Table 1 summarizes the datasets.
Table 1.
Statistics of the datasets used in our experiments.
For all three datasets, we use the pre-extracted text, audio, and visual features provided through the MMSA framework [32]. Modality-specific projection layers map these features into a common latent space before shared-private decomposition and text- guided interaction.
4.1.2. Evaluation Metrics
For CMU-MOSI and CMU-MOSEI, we report the mean absolute error (MAE), the Pearson correlation coefficient (Corr), five-class accuracy (Acc-5), seven-class accuracy (Acc-7), binary accuracy (Acc-2), and the F1 score. Unless otherwise specified, Acc-2 and F1 exclude samples with zero sentiment labels, following common MSA evaluation protocols. For CH-SIMS, we report MAE, Acc-2, Acc-5, and F1. MAE measures the absolute error between predicted and ground-truth sentiment scores, while Corr measures their linear association. Classification metrics are computed by mapping continuous scores to discrete sentiment categories according to standard evaluation protocols. Lower MAE and higher values of the other metrics indicate better performance.
4.1.3. Implementation Details
All experiments used Python 3.6.13, PyTorch 1.10.2, CUDA 11.3, and cuDNN 8.2. They were run on a workstation with a single NVIDIA GeForce RTX 3090 GPU with 24 GB of memory. Table 2 summarizes the main settings.
Table 2.
Main hyperparameter settings of the proposed model.
4.2. Comparison with State-of-the-Art Methods
We evaluate the proposed method on CMU-MOSI, CMU-MOSEI, and CH-SIMS against representative approaches from different lines of multimodal sentiment analysis research. Early fusion and interaction-based models include TFN [5], LMF [6], MFN [44], and MulT [7]. Representation learning and disentanglement-based methods include MISA [9], Self-MM [32], and DMD [11]. Recent approaches to text-guided representation learning, modality decoupling, and contrastive multimodal optimization include ALMT [14], MVCF [45], PriSA [19], DLF [41], MECAM [46], MFON [47], and MISA-GMC [48].
ALMT and MFON provide relevant external comparisons for the text-guided interaction and contrastive representation learning aspects of our framework. ALMT uses language-guided adaptive hyper-modality learning to suppress irrelevant or conflicting audio-visual information, while MFON combines prompt-guided modality feature optimization with inter-modal contrastive learning. We reproduce both methods on all three datasets using the same multimodal features, dataset splits, and training protocol as our method. Results for the remaining baselines are taken from their respective publications, providing broader coverage of MSA approaches. Table 3 and Table 4 report the results and identify the reproduced baselines.
Table 3.
Comparison with state-of-the-art methods on CMU-MOSI and CMU-MOSEI. “-” indicates that the result is not reported in the original paper. Results of our method and the reproduced ALMT and MFON baselines are reported as mean ± standard deviation over three random seeds; classification means are percentages, and their standard deviations are in percentage points. The best reported mean for each metric is highlighted in bold, and the second-best mean is underlined. Tied second-best results are all underlined. ↑ indicates that higher values are better, whereas ↓ indicates that lower values are better.
Table 4.
Comparison with state-of-the-art methods on CH-SIMS. “-” indicates that the result is not reported in the original paper. Results of our method and the reproduced ALMT and MFON baselines are the mean ± standard deviation over three random seeds; classification means are percentages, and their standard deviations are in percentage points. The best reported mean for each metric is highlighted in bold. ↑ indicates that higher values are better, whereas ↓ indicates that lower values are better.
Table 3 reports the results on the English benchmarks. On CMU-MOSI, our method achieves the lowest MAE of 0.708 and the highest Acc-5 of 55.4. It also shares the best Acc-7 and Acc-2 scores of 47.3 and 85.8, respectively, and achieves competitive Corr and F1 scores of 0.793 and 85.7. Relative to the published PriSA results [19], MAE decreases from 0.714 to 0.708 and Acc-5 increases from 52.5 to 55.4; Acc-7 is unchanged, while Acc-2 and F1 improve. Our method also improves all reported metrics relative to DLF [41], including a reduction in MAE from 0.731 to 0.708 and increases in Acc-5 and Acc-7 from 52.3 and 47.1 to 55.4 and 47.3. Under the controlled reproduction protocol, it outperforms ALMT on all reported metrics and MFON on all metrics except Corr. These results indicate strong fine-grained classification performance alongside competitive regression and binary classification.
On CMU-MOSEI, our method achieves the highest Acc-5, Acc-7, Acc-2, and F1 among the listed results, at 56.7, 54.8, 86.3, and 86.2, respectively. It also achieves the second-lowest MAE of 0.527 and a competitive Corr of 0.771. The corresponding classification scores for PriSA are 56.2, 54.7, 85.9, and 85.9 [19]. Our method improves all reported metrics over the reproduced ALMT and MFON baselines except Corr, where it remains competitive. It also outperforms the published DLF [41], MECAM [46], and MISA-GMC [48] results on every reported metric. These findings support the effectiveness of the framework on the larger English benchmark.
The proposed method improves most metrics relative to classical fusion methods, including TFN [5], LMF [6], MFN [44], and MulT [7]. These methods combine modalities through tensor operations, low-rank approximations, memory mechanisms, or cross-modal attention, generally without explicit shared-private separation. Our framework introduces this separation before interaction, providing a structured basis for sentiment-oriented fusion and alignment.
Compared with MISA [9], Self-MM [32], and DMD [11], our method additionally applies label-aware distributional alignment to the audio–text and visual–text interaction views. LA-GCA-UOT uses soft sentiment neighborhoods and polarity consistency to organize these views according to the relations encoded by continuous labels.
The strongest gains occur in fine-grained classification, consistent with the design of label-aware alignment. MAE measures numerical prediction error and Corr measures linear association, whereas Acc-5 and Acc-7 depend on assigning predictions to the correct sentiment-intensity intervals. Soft neighborhood relations encourage nearby sentiment scores to have related representations, while the polarity mask restricts alignment across the negative/non-negative boundary. This provides a possible explanation for the improvements in fine-grained classification. Competitive MAE on CMU-MOSI and CMU-MOSEI further indicates that these gains do not come at the cost of substantially larger numerical errors.
On CH-SIMS, our method achieves the best results on all reported metrics, with MAE of 0.405, Acc-2 of 80.4, F1 of 80.6, and Acc-5 of 42.8 (Table 4). Relative to the strongest baseline for each metric, MAE decreases from 0.426 to 0.405, Acc-2 increases from 79.0 to 80.4, F1 increases from 79.7 to 80.6, and Acc-5 increases from 40.5 to 42.8. These results extend the evidence for the framework to Chinese sentiment prediction.
The results on CH-SIMS support the applicability of the same representation-and-alignment design to the evaluated English and Chinese benchmarks. Models are trained separately for each dataset using language-appropriate pretrained text representations: English representations for CMU-MOSI and CMU-MOSEI and Chinese representations for CH-SIMS. These learned textual representations supply the semantic reference for cross-modal interaction. The central role of text is also reflected in the text-input masking results in Section 4.3.2.
Overall, the results show competitive regression performance and strong fine-grained sentiment classification across the three benchmarks. The following ablations examine how the representation and alignment components contribute to this performance.
4.3. Ablation Study
To evaluate the contribution of each key component across dataset scales and language settings, we conduct structural and LA-GCA-UOT component ablations on CMU-MOSI, CMU-MOSEI, and CH-SIMS. CMU-MOSI and CMU-MOSEI provide English benchmarks at different scales, while CH-SIMS extends the analysis to Chinese sentiment prediction. Within each dataset, the ablations retain the experimental settings of the complete model apart from the component being examined. CH-SIMS results are averaged over three runs using the same seeds for the complete model and all ablation variants. Additional modality-input and contrastive-objective analyses are conducted on CMU-MOSI and CMU-MOSEI. The mechanisms underlying the observed effects are discussed in Section 5.
4.3.1. Effects of Structural Components
To examine the contribution of each key design, we construct variants by removing shared-private decoupling, replacing TGCE with a simplified text-conditioned alternative, or removing the Label-Aware GCA-UOT contrastive learning branch under otherwise unchanged settings. The results are shown in Table 5. These variants examine the roles of representation decoupling, TGCE-based interaction-view construction, and label-aware distributional alignment, respectively.
Table 5.
Structural ablation study on CMU-MOSI, CMU-MOSEI, and CH-SIMS. CH-SIMS entries are the means over three matched-seed runs. The best result for each metric within each dataset is highlighted in bold, including ties at the displayed precision. ↑ indicates that higher values are better, whereas ↓ indicates that lower values are better.
As shown in Table 5, the full model achieves the best MAE, Acc-5, Acc-7, and F1 and tied-best Acc-2 on CMU-MOSI, and it achieves the best or tied-best results across all reported metrics on CMU-MOSEI. On CH-SIMS, it achieves the highest Acc-5 of 42.8%. Removing decoupling, TGCE, or the contrastive learning branch reduces Acc-5 to 40.8%, 40.5%, and 40.8%, respectively. These results support the contribution of each design to fine-grained sentiment classification across the three benchmarks.
The CH-SIMS ablations reveal trade-offs across metrics. Removing decoupling or TGCE improves MAE, Acc-2, and F1 but reduces Acc-5. Removing the contrastive branch improves MAE while lowering all three classification scores. Removing both decoupling and the contrastive branch gives MAE of 0.408 and Acc-5 of 42.7%, with worse performance than the complete model on all four metrics. The smaller Acc-5 decrease under joint removal than under either individual removal suggests that the components interact. The complete framework’s clearest advantage on CH-SIMS is fine-grained classification.
4.3.2. Effects of Different Features and Modalities
To analyze the contribution of each input modality within the proposed framework, we conduct modality-input masking ablations while retaining the full model architecture. For each variant, the input features of one modality are set to zero throughout training, validation, and testing, and the model is independently retrained under this condition. Training and evaluation therefore use the same input-masking condition. A related fixed-architecture ablation strategy was used in MMCL, which zeroed the corresponding modality representations [35].
Keeping the masked branches in place preserves the architecture while isolating the contribution of the corresponding input information. In addition, we remove the private representations from the final fusion to examine whether modality-specific complementary cues provide useful information beyond the interaction representations. The results are shown in Table 6.
Table 6.
Ablation study on input modalities and private representations on CMU-MOSI and CMU-MOSEI. Each input-masked variant is independently retrained with the specified modality input set to zero during training, validation, and testing, while retaining the full architecture. The best result for each metric within each dataset is highlighted in bold, including ties. ↑ indicates that higher values are better, whereas ↓ indicates that lower values are better.
As shown in Table 6, masking the text input and retraining causes the largest performance drop on both datasets, supporting the central contribution of textual information within the proposed text-guided framework. Masking audio or visual inputs also reduces performance despite retraining, although the decreases are smaller. These results support the contributions of all three input modalities to sentiment prediction within this framework.
Removing private representations has mixed effects on CMU-MOSEI: the variant remains competitive on several metrics but performs worse on Acc-7, Acc-2, and F1. On CMU-MOSI, performance decreases across all reported metrics. These results suggest that the interaction views capture much of the shared sentiment information, while private representations add useful affective cues, particularly on the smaller dataset.
4.3.3. Component Analysis of LA-GCA-UOT
To further analyze the contribution of each component in LA-GCA-UOT, we conduct an ablation study by modifying the internal terms of the proposed objective. Specifically, we examine the explicit pairwise alignment term , the soft distributional alignment term , the label-aware relation in the target transport distribution, and the negative/non-negative polarity mask. The results are shown in Table 7.
Table 7.
Component analysis of LA-GCA-UOT on CMU-MOSI, CMU-MOSEI, and CH-SIMS. CH-SIMS entries are the means over three matched-seed runs. The best result for each metric within each dataset is highlighted in bold, including ties at the displayed precision. ↑ indicates that higher values are better, whereas ↓ indicates that lower values are better.
In w/o , we set and retain , removing the explicit paired-view loss while preserving paired correspondence in . In w/o , we set , leaving only explicit paired-view alignment. In w/o label-aware relation, we set , removing the label-distance relations from the target; the polarity mask then has no effect. In w/o polarity mask, we retain the label-aware relations but allow them across the negative/non-negative boundary.
As shown in Table 7, the complete LA-GCA-UOT achieves the best or tied-best results on most metrics on CMU-MOSI and CMU-MOSEI. On CH-SIMS, removing , , the label-aware relation, or the polarity mask reduces Acc-5 from 42.8% to 40.0%, 40.6%, 40.2%, and 41.6%, respectively. The decreases of 2.8, 2.2, 2.6, and 1.2 percentage points, calculated from the displayed means, support the contribution of all four components to fine-grained sentiment classification in the Chinese benchmark.
Removing the paired loss, soft distributional loss, or polarity mask also worsens the other three CH-SIMS metrics. Removing the label-aware relation improves Acc-2 and F1 and leaves MAE unchanged at the reported precision of 0.405, but it substantially reduces Acc-5. Thus, the clearest benefit of label-aware relations on CH-SIMS is finer discrimination of sentiment intensity. Across the three datasets, the results support combining paired correspondence, graded label proximity, and polarity consistency.
4.3.4. Comparison with Different Contrastive Objectives
We compare LA-GCA-UOT with related objectives using the same backbone and training protocol. The w/o Contrastive Learning variant removes the entire contrastive branch. Distance-aware CL uses label-distance supervision without OT-based matching, while vanilla GCA-UOT uses distributional alignment without a sentiment-aware target. Table 8 reports the results.
Table 8.
Comparison with different contrastive objectives on CMU-MOSI and CMU-MOSEI. The best result for each metric within each dataset is highlighted in bold, including ties. ↑ indicates that higher values are better, whereas ↓ indicates that lower values are better.
LA-GCA-UOT achieves the strongest overall results in Table 8. On CMU-MOSEI, it leads on every metric. On CMU-MOSI, it achieves the lowest MAE, the highest Acc-5, Acc-7, and F1, and joint-best Acc-2. These results support the complete objective over the alternatives evaluated here.
The comparisons examine two complementary aspects of LA-GCA-UOT. Distance-aware CL supplies pairwise label-distance supervision, while vanilla GCA-UOT supplies distributional transport alignment with a paired-view target. LA-GCA-UOT combines continuous-label relations with distributional matching and improves all six reported metrics over both alternatives on CMU-MOSI and CMU-MOSEI. Because the input features, representation backbone, and training protocol are shared, these results directly support the effectiveness of the proposed alignment objective.
Together, the external-model reproductions, objective comparisons, and component ablations evaluate the method at three levels. ALMT and MFON provide complete-model comparisons across the three benchmarks. The same-backbone objective comparisons assess closely related alignment alternatives, and the component ablations identify the contributions of the target and loss terms. The consistent fine-grained classification gains across these controlled comparisons support the contribution of label-aware distributional alignment to the complete framework.
4.3.5. Sensitivity to Target-Distribution Hyperparameters
Following the variational characterization in Proposition 1, we empirically examine the target-distribution parameters. Under ideal row normalization, only the ratio matters, so we fix as the reference scale. The parameters and control the relative contribution of non-paired relations and their selectivity with respect to label distance, respectively.
We examine local sensitivity on CMU-MOSEI around the default setting . With , we vary at and at . The two parameters are varied one at a time. Each setting is evaluated over three runs using the same random seeds as the main baseline comparisons. Table 9 reports the mean results, with the original default result included as a reference.
Table 9.
Local sensitivity to target-distribution hyperparameters on CMU-MOSEI with . Entries are the means over three runs using the same random seeds as the main baseline comparisons; classification metrics are percentages. The default row reproduces the main-result reference at its original precision. ↑ indicates that higher values are better, whereas ↓ indicates that lower values are better.
With , the default produces better mean results than 0.05 or 0.2 on all six metrics, favoring an intermediate weight for non-paired relations among the tested settings. With , MAE stays within approximately 0.527–0.528 and Corr within approximately 0.771–0.772 across the tested bandwidths. The default bandwidth gives the highest classification scores, while gives the highest Corr. These results support the default as a useful balance between regression and classification within the tested CMU-MOSEI range.
The parameter settings for all three datasets are listed in Table 2. We use for CMU-MOSI and CMU-MOSEI, whose sentiment labels range over , and for CH-SIMS, whose labels range over . The smaller bandwidth on CH-SIMS is consistent with its narrower label scale, since the affinity depends on the ratio .
4.3.6. Sensitivity to Training-Label Noise
To evaluate the dependence of LA-GCA-UOT on annotation reliability, we perturb all continuous training labels on CMU-MOSEI and compare the complete model with the variant without label-aware relations (). For each original label , we generate
where the noise is sampled independently and is measured on the normalized label scale. We use to distinguish the noise standard deviation from the label-affinity bandwidth in the target distribution. Before clipping, these settings correspond to standard deviations of 0.15 and 0.30 on the original label scale.
The corrupted labels are generated once before training and remain fixed throughout all epochs of a run. Both the main regression objective and the private-branch auxiliary regression objectives use these labels. The complete model also uses the same corrupted labels to compute label similarities and polarity masks when constructing its target transport distribution. For each seed and noise level, the complete and models use identical corrupted labels. Validation and test labels remain unchanged. The training batch size is 64 and the early stopping patience is 5. For each nonzero noise level, we report the mean over seeds 694, 3480, and 2021. Table 10 also includes the existing noise-free results under the same training settings as a reference.
Table 10.
Sensitivity to training-label noise on CMU-MOSEI. The noise standard deviation is defined on labels normalized to . Entries report mean performance. Nonzero-noise results are averaged over three seeds; the noise-free rows reproduce the means in Table 7. Acc-2 and F1 exclude zero-label samples, and all classification metrics are percentages. Bold values indicate the better mean within each noise level. ↑ indicates that higher values are better, whereas ↓ indicates that lower values are better.
At , the complete model retains an advantage over in regression and fine-grained classification: MAE decreases by 0.0116, Corr increases by 0.0055, and Acc-5 and Acc-7 improve by 1.43 and 1.38 percentage points, respectively. Its performance also remains close to the noise-free reference, with MAE changing from 0.527 to 0.5287 and Acc-5 from 56.7% to 56.21%. These results indicate that label-aware relations can still provide useful supervision at the lower tested noise level. The nonzero binary metrics are nearly unchanged between the two variants, so the benefit is not uniform across all metrics.
At , both variants perform worse than at . The complete model’s MAE advantage over falls to 0.0008, while Corr and the classification means slightly favor . Because the variants use identical corrupted regression labels, this comparison isolates the additional contribution of label-aware relations under the same annotation noise. Their benefit is retained at the lower tested noise level but diminishes under stronger corruption, indicating a dependence on annotation reliability.
4.3.7. Sensitivity to the Number of Samples Used for Relation Computation
The number of samples participating in each relation computation determines the available cross-sample neighborhood in LA-GCA-UOT. To isolate this effect, we fix the training batch size at 64 on CMU-MOSEI and vary the relation scope . For or 32, the same training batch is randomly partitioned into four or two disjoint groups, respectively; UOT, the target distribution, and the alignment loss are computed separately within each group. For , the original full-batch relation computation is retained. Group alignment losses are averaged with weights proportional to group sample counts, preserving the overall alignment-loss weight. The training batch size and early stopping patience of 5 are unchanged, and results are summarized over seeds 694, 3480, and 2021.
Table 11 shows that gives the best mean on every reported metric. Relative to , it reduces MAE from 0.532 to 0.527 and increases Acc-5 and Acc-7 by 0.7 and 0.6 percentage points, respectively. The response is not monotonic: performs worse than on MAE, Corr, Acc-5, and Acc-7 but slightly better on the binary metrics. These results favor full-batch relation computation for the evaluated configuration. Keeping the training batch size and alignment-loss weight fixed allows the comparison to focus on the number of samples used to compute relations.
Table 11.
Sensitivity to relation computation scope on CMU-MOSEI with a fixed training batch size of 64. Results are the means ± sample standard deviations over three seeds. Acc-2 and F1 exclude zero-label samples, and all classification metrics are percentages. The best mean for each metric is highlighted in bold. ↑ indicates that higher values are better, whereas ↓ indicates that lower values are better.
4.3.8. Sensitivity to Batch Neighborhood Quality
To evaluate the dependence of label-aware alignment on batch composition, we compare the complete model with its variant on CMU-MOSEI using batches rearranged to reduce effective sentiment-neighborhood mass. For sample i in epoch e, let denote its batch. Following the parameter analysis of Equation (12), we measure the available off-diagonal affinity by
We use the original CMU-MOSEI labels, preserving their values throughout the experiment. This measure excludes self-relations and sums the affinities of same-polarity neighbors, with zero labels assigned to the non-negative group. It is computed for both model variants using the same labels and batch indices, independently of the value of .
For each seed and epoch, we first generate a random sample permutation and apply drop_last=True. This defines the used set , containing 16,320 samples in 255 batches of size 64, and the six omitted samples. Candidate batch assignments are obtained by exchanging used samples across batches. Each sample in occurs exactly once, and the omitted set remains fixed. Let and denote the neighborhood masses before and after the exchanges. We define
Thus, the reduction is measured relative to the original random batches for the same seed, epoch, and used sample set. An exchange is accepted only when it lowers the total neighborhood mass over .
We evaluate two exchange policies. The targeted policy stops when the reduction reaches the prescribed 2.00–2.05% interval, subject to a maximum of attempted exchanges per epoch. Its observed reductions during training were 2.000–2.005%. The fixed-budget policy performs exchange attempts per epoch; the reduction is an outcome of the search.
For each policy, the complete model and the variant use identical batch indices for each matched seed and epoch. The batch size, used and omitted sample sets, and number of optimizer updates remain fixed within each epoch, with 1 update per batch and 255 updates in total. Early stopping is applied independently to each run, so total training lengths may differ. Table 12 reports the means and sample standard deviations over three seeds for each model and policy.
Table 12.
Sensitivity to batch neighborhood quality on CMU-MOSEI. Results are the means ± sample standard deviations over three seeds; classification metrics are percentages. Bold indicates the better mean within each exchange policy. The targeted policy achieved a 2.000–2.005% reduction during training. ↑ indicates that higher values are better, whereas ↓ indicates that lower values are better.
Under the targeted 2% policy, the complete model improves all four reported means over : MAE decreases by 0.0059, and Acc-5, Acc-7, and Acc-2 increase by 0.24, 0.52, and 0.15 percentage points, respectively. Label-aware relations therefore retain predictive benefits under this controlled reduction in neighborhood mass. Under the fixed-budget policy, the MAE advantage is 0.0022, while Acc-5, Acc-7, and Acc-2 are lower by 0.20, 0.18, and 0.03 percentage points. The classification benefit is consequently absent in the reported means for this policy. Together, the matched-model comparisons show that the additional benefit of label-aware alignment depends on the batch composition induced by the exchange policy, providing empirical support for the role of available sentiment neighbors.
4.4. Visualization Analysis
4.4.1. Visualization of LA-GCA-UOT Matching Patterns
We visualize the row-normalized transport distribution on CMU-MOSEI before and after alignment optimization to examine the learned cross-view matching patterns. Rows correspond to visual–text representations , and columns correspond to audio–text representations . Each entry gives the transport weight from a source visual–text view to a target audio–text view. Diagonal entries link the two views of the same utterance.
Both panels use the same test mini-batch, the same label-based ordering of rows and columns, and a common color scale. Corresponding positions therefore refer to the same sample pairs, and their weights can be compared directly. Sorting by ground-truth label places utterances with similar sentiment scores near one another along both axes.
In Figure 2, weights in the initial panel are more dispersed, whereas the later panel shows more pronounced weights at paired positions and in parts of the label-adjacent regions. Under the fixed ordering and common color scale, these differences illustrate changes in the allocation of transport mass for the displayed batch. The diagonal entries correspond to paired views of the same utterance; off-diagonal entries show how the remaining mass is distributed among other samples.
Figure 2.
Row-normalized cross-view transport distributions on CMU-MOSEI at the initial epoch and after optimization. Rows denote visual–text views and columns denote audio–text views. Both panels use the same samples, the same ordering by ground-truth label on both axes, and a common color scale; brighter entries indicate larger weights. Diagonal entries represent paired views of the same utterance. Label sorting places similar-label samples near one another for display; corresponding positions in the two panels show changes in transport mass under this fixed ordering.
The heatmaps provide a qualitative illustration of the learned coupling, complementing the prediction results and the component and objective comparisons in Section 4.3.3 and Section 4.3.4.
4.4.2. Visualization of Text-Guided Interaction Representations
We use t-SNE to visualize the audio–text representations and visual–text representations for the entire CMU-MOSEI test set. The plots before and after training use the same samples and a fixed t-SNE random state. Point colors indicate ground-truth sentiment intensity, from lower values for negative sentiment to higher values for positive sentiment.
Figure 3 shows that sentiment regions overlap considerably before training. After training, both and exhibit clearer organization by sentiment: samples with similar intensities tend to lie closer together, and negative and positive samples are more distinguishable.
Figure 3.
t-SNE visualization of the text-guided interaction representations on CMU-MOSEI. All four panels use the entire test set and a fixed t-SNE random state: (a,b) show the audio–text interaction representation , while (c,d) show the visual–text interaction representation . Colors indicate ground-truth sentiment intensity.
This qualitative observation is consistent with the quantitative improvements reported above. Since and are constructed through text-guided interaction and further regularized by LA-GCA-UOT, the trained interaction space is encouraged to preserve both cross-modal correspondence and sentiment-related local structure. As t-SNE is a two-dimensional projection of high-dimensional representations and may be affected by projection hyperparameters, the visualization is used only as complementary qualitative evidence.
5. Discussion
5.1. Structured Representations for Effective Cross-Modal Interaction
The proposed framework suggests that effective multimodal sentiment learning depends on both cross-modal interaction and the structure of the representations being exchanged. Fusion methods show that richer information exchange can improve prediction [5,6,7,8]. However, when shared sentiment information is entangled with modality-specific variation, interaction may propagate irrelevant information along with affective cues. Greater interaction capacity alone does not necessarily organize representations around sentiment.
Shared-private representation learning addresses this issue by separating common semantic information from complementary modality-specific cues [9,11,33,41]. Shared representations support information exchange, while private representations preserve acoustic, visual, and textual information that is not fully captured in a common space [49]. In our framework, this decomposition determines which information reaches each stage: shared representations enter cross-modal interaction, and private representations contribute directly to prediction.
The three stages serve successive roles. Shared-private decomposition organizes information within each modality. Text-guided interaction then constructs audio–text and visual–text views from the shared representations using a common textual reference. LA-GCA-UOT aligns these views across samples. The framework thus connects within-modality decomposition, cross-modal interaction, and cross-sample relational supervision.
The structural ablations examine the roles of representation decoupling, text-guided interaction, and LA-GCA-UOT across the three datasets. The complete model achieves the highest Acc-5 in every structural comparison. On CMU-MOSI and CMU-MOSEI, the benefits extend to most regression and binary classification metrics. On CH-SIMS, retaining decoupling, TGCE, and the contrastive learning branch favors fine-grained sentiment classification, while some simplified variants achieve lower MAE or higher binary scores. The joint removal of decoupling and the contrastive learning branch produces a smaller Acc-5 decrease than either individual removal on CH-SIMS, showing that their effects depend on the remaining framework. These findings support their contribution to fine-grained discrimination while revealing dataset-dependent interactions and trade-offs among prediction metrics.
The modality ablations further clarify the contributions of text guidance and non-text inputs within the proposed framework. The largest performance degradation occurs when text is masked, consistent with its role as the semantic reference in the interaction stage. The performance decreases under audio and visual masking, even after independent retraining, further support the contributions of these modalities. The decrease caused by removing private representations also suggests that modality-private cues provide useful information beyond the shared interaction views.
The experiments assess these roles at complementary levels. Structural ablations evaluate the representation and interaction stages, while objective comparisons using the same backbone and target-component ablations evaluate the alignment extension. The fine-grained classification results support both the complete framework and the additional value of continuous-label supervision. Effects on individual metrics depend on the dataset and the components retained.
5.2. Label-Aware Distributional Alignment for Fine-Grained Sentiment Learning
The comparison of Distance-aware CL, vanilla GCA-UOT, and LA-GCA-UOT examines two forms of relational supervision. Distance-aware CL weights pairwise constraints by sentiment-label proximity, without learning a joint coupling between the view sets. Vanilla GCA-UOT learns a batch-level coupling but uses a paired-instance target that does not distinguish off-diagonal relations by sentiment label [27]. LA-GCA-UOT combines these properties by using label relations to define the target structure of the transport plan. Its improvements over both alternatives with the same backbone support this combination in the evaluated setting.
The label-aware target converts continuous annotations into relational supervision for the entire mini-batch. It assigns a dedicated weight to the paired audio–text and visual–text views of each utterance. For non-paired samples, weights decrease with sentiment-score distance, and the polarity mask excludes relations across the negative/non-negative boundary. The target therefore specifies both which views belong to the same utterance and how views from different utterances should be related. Continuous labels supervise the cross-view matching structure in addition to individual predictions.
Entropic unbalanced OT provides a flexible mechanism for learning this matching structure. Whereas conventional anchor-wise objectives normalize relations separately for each anchor, UOT jointly learns the entries of a batch-level coupling. Entropic regularization discourages concentration on only a few minimum-cost matches, allowing the coupling to represent both paired and weaker off-diagonal relations. It also supports efficient Sinkhorn-type optimization [23]. Marginal relaxation allows row and column masses to deviate from uniform reference marginals, reducing the need to retain weak matches merely to satisfy fixed constraints [26]. The label-aware target specifies the desired sentiment relations, while entropy regularization and marginal relaxation govern how flexibly the coupling can represent them.
The component analysis supports the complementary roles of the two loss terms. The paired-view loss reinforces correspondence between views of the same utterance, while the soft distributional loss guides the row-normalized coupling toward the label-aware target. Removing the paired-view loss weakens explicit instance-level supervision; removing the soft loss or label-aware relations reduces supervision from graded sentiment neighborhoods. The polarity mask further restricts those neighborhoods to samples with consistent polarity. Although individual metrics respond differently, the complete configuration provides the most consistent overall performance.
The Acc-5 and Acc-7 gains are consistent with the finer relational structure encoded by the target. Label-distance weights distinguish degrees of similarity among non-paired samples, and the polarity mask excludes relations across the negative/non-negative boundary. Paired-view and regression losses continue to supervise instance correspondence and continuous score prediction. On CH-SIMS, adding label-aware relations increases Acc-5 from 40.2% to 42.8%, while MAE is unchanged at the displayed precision and binary scores decrease. Sentiment-intensity discrimination is therefore the most consistent benefit, with regression and classification trade-offs varying by dataset.
More broadly, LA-GCA-UOT uses continuous labels to supervise both individual predictions and distributional alignment. Its target jointly encodes paired correspondence and graded relations among non-paired samples. Entropic regularization supports a soft coupling, and unbalanced transport accommodates variation in cross-view correspondence without fixed marginal matching. This formulation offers a basis for exploring distributional alignment in other tasks with continuous or ordered annotations.
5.3. Limitations and Boundary Conditions
LA-GCA-UOT depends on the reliability of the annotations used to construct its target. In standard regression, a label directly supervises the prediction for one sample. Here, it also defines relations between that sample and others in the mini-batch. Noisy or inconsistent annotations may therefore distort both prediction and relational supervision. Section 4.3.6 examines this dependence. At , the complete model remains close to its noise-free performance and outperforms on MAE, Corr, and fine-grained classification. At , its MAE advantage falls to 0.0008, and the other reported means slightly favor . Stronger annotation noise thus reduces the additional benefit of label-aware relations in the tested setting.
Mini-batch composition also affects the label-aware neighborhood. Samples in densely populated sentiment regions have more nearby neighbors, whereas rare or extreme scores may have fewer. Section 4.3.7 varies the number of samples used to compute relations, and Section 4.3.8 rearranges fixed-size batches to reduce same-polarity neighborhood mass. With the targeted 2% reduction, the complete model outperforms on all four reported means. With the fixed exchange budget, its MAE advantage is smaller and the classification means slightly favor . These results link the value of relational supervision to the available batch neighborhoods. Future work could examine label imbalance by explicitly controlling the frequencies of sentiment groups within batches.
The polarity mask separates negative samples from non-negative samples, including neutral utterances. Graded polarity weights could provide a more flexible treatment of expressions near the neutral boundary.
The text-guided interaction mechanism relies on the quality of the textual semantic reference. Future work will investigate reliability-aware interaction for ambiguous or sarcastic expressions.
6. Conclusions
We present a framework for fine-grained multimodal sentiment prediction that combines shared-private representation learning, text-guided interaction, and GCA-UOT. Shared representations form audio–text and visual–text interaction views, while private representations retain complementary cues for prediction. The methodological extension is a target transport distribution derived from continuous labels. By combining paired correspondence, sentiment-intensity proximity, and polarity consistency, this target introduces graded sentiment relations into cross-view distributional alignment.
Experiments on CMU-MOSI, CMU-MOSEI, and CH-SIMS support the effectiveness of the framework, with the most consistent gains in fine-grained sentiment classification. Ablations show the contributions of representation decomposition, TGCE, private cues, label-aware relations, and polarity masking, while also revealing dataset-dependent trade-offs across metrics. Visualizations provide complementary evidence of more structured cross-view matching and clearer organization by sentiment. Future work will investigate reliability-aware alignment by estimating the confidence of the audio–text and visual–text views and incorporating it into the transport coupling. The aim is to reduce the influence of noisy or conflicting modality information under imperfect input conditions.
Author Contributions
Conceptualization, M.W. and C.W.; methodology, M.W.; software, M.W.; validation, M.W.; formal analysis, M.W. and X.M.; investigation, M.W.; data curation, M.W.; writing—original draft preparation, M.W. and X.M.; writing—review and editing, M.W., X.M. and C.W.; visualization, M.W.; supervision, C.W.; project administration, C.W. All authors have read and agreed to the published version of the manuscript.
Funding
This research was supported by the “Effectiveness Testing of Domain-Specific Intelligent Algorithms” project (No. 200-662504060).
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The CMU-MOSI, CMU-MOSEI, and CH-SIMS datasets and the processed multimodal features analyzed in this study are publicly available through the MMSA repository at https://github.com/thuiar/MMSA (accessed on 30 July 2026). No new datasets were created in this study.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Zadeh, A.; Zellers, R.; Pincus, E.; Morency, L.P. MOSI: Multimodal Corpus of Sentiment Intensity and Subjectivity Analysis in Online Opinion Videos. arXiv 2016, arXiv:1606.06259. [Google Scholar] [CrossRef] [Scilit]
- Bagher Zadeh, A.; Liang, P.P.; Poria, S.; Cambria, E.; Morency, L.P. Multimodal Language Analysis in the Wild: CMU-MOSEI Dataset and Interpretable Dynamic Fusion Graph. In Proceedings of the 56th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers); Association for Computational Linguistics: Stroudsburg, PA, USA, 2018; pp. 2236–2246. [Google Scholar] [CrossRef] [Scilit]
- Yu, W.; Xu, H.; Meng, F.; Zhu, Y.; Ma, Y.; Wu, J.; Zou, J.; Yang, K. CH-SIMS: A Chinese Multimodal Sentiment Analysis Dataset with Fine-grained Annotation of Modality. In Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics; Association for Computational Linguistics: Stroudsburg, PA, USA, 2020; pp. 3718–3727. [Google Scholar] [CrossRef] [Scilit]
- Soleymani, M.; Garcia, D.; Jou, B.; Schuller, B.; Chang, S.F.; Pantic, M. A Survey of Multimodal Sentiment Analysis. Image Vis. Comput. 2017, 65, 3–14. [Google Scholar] [CrossRef] [Scilit]
- Zadeh, A.; Chen, M.; Poria, S.; Cambria, E.; Morency, L.P. Tensor Fusion Network for Multimodal Sentiment Analysis. In Proceedings of the 2017 Conference on Empirical Methods in Natural Language Processing; Association for Computational Linguistics: Stroudsburg, PA, USA, 2017; pp. 1103–1114. [Google Scholar] [CrossRef] [Scilit]
- Liu, Z.; Shen, Y.; Lakshminarasimhan, V.B.; Liang, P.P.; Bagher Zadeh, A.; Morency, L.P. Efficient Low-rank Multimodal Fusion With Modality-Specific Factors. In Proceedings of the 56th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers); Association for Computational Linguistics: Stroudsburg, PA, USA, 2018; pp. 2247–2256. [Google Scholar] [CrossRef] [Scilit]
- Tsai, Y.H.H.; Bai, S.; Liang, P.P.; Kolter, J.Z.; Morency, L.P.; Salakhutdinov, R. Multimodal Transformer for Unaligned Multimodal Language Sequences. In Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics; Association for Computational Linguistics: Stroudsburg, PA, USA, 2019; pp. 6558–6569. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Rahman, W.; Hasan, M.K.; Lee, S.; Bagher Zadeh, A.; Mao, C.; Morency, L.P.; Hoque, E. Integrating Multimodal Information in Large Pretrained Transformers. In Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics; Association for Computational Linguistics: Stroudsburg, PA, USA, 2020; pp. 2359–2369. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Hazarika, D.; Zimmermann, R.; Poria, S. MISA: Modality-Invariant and -Specific Representations for Multimodal Sentiment Analysis. In Proceedings of the 28th ACM International Conference on Multimedia; Association for Computing Machinery: New York, NY, USA, 2020; pp. 1122–1131. [Google Scholar] [CrossRef] [Scilit]
- Yang, D.; Huang, S.; Kuang, H.; Du, Y.; Zhang, L. Disentangled Representation Learning for Multimodal Emotion Recognition. In Proceedings of the 30th ACM International Conference on Multimedia; Association for Computing Machinery: New York, NY, USA, 2022; pp. 1642–1651. [Google Scholar] [CrossRef] [Scilit]
- Li, Y.; Wang, Y.; Cui, Z. Decoupled Multimodal Distilling for Emotion Recognition. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Vancouver, BC, Canada, 17–24 June 2023; pp. 6631–6640. [Google Scholar]
- Yang, J.; Yu, Y.; Niu, D.; Guo, W.; Xu, Y. ConFEDE: Contrastive Feature Decomposition for Multimodal Sentiment Analysis. In Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers); Association for Computational Linguistics: Stroudsburg, PA, USA, 2023; pp. 7617–7630. [Google Scholar] [CrossRef] [Scilit]
- Wang, D.; Guo, X.; Tian, Y.m.; Liu, J.; He, L.; Luo, X. TETFN: A Text Enhanced Transformer Fusion Network for Multimodal Sentiment Analysis. Pattern Recognit. 2023, 136, 109259. [Google Scholar] [CrossRef] [Scilit]
- Zhang, H.; Wang, Y.; Yin, G.; Liu, K.; Liu, Y.; Yu, T. Learning Language-guided Adaptive Hyper-modality Representation for Multimodal Sentiment Analysis. In Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing, Singapore, 6–10 December 2023; pp. 756–767. [Google Scholar] [CrossRef] [Scilit]
- Chen, J.; Song, S.; Tan, Y.; Xia, H. TEMSA: Text Enhanced Modal Representation Learning for Multimodal Sentiment Analysis. Comput. Vis. Image Underst. 2025, 258, 104391. [Google Scholar] [CrossRef] [Scilit]
- Su, Y.; Zhao, X. Hierarchical Text-Guided Refinement Network for Multimodal Sentiment Analysis. Entropy 2025, 27, 834. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- van den Oord, A.; Li, Y.; Vinyals, O. Representation Learning with Contrastive Predictive Coding. arXiv 2018, arXiv:1807.03748. [Google Scholar] [CrossRef] [Scilit]
- Khosla, P.; Teterwak, P.; Wang, C.; Sarna, A.; Tian, Y.; Isola, P.; Maschinot, A.; Liu, C.; Krishnan, D. Supervised Contrastive Learning. Adv. Neural Inf. Process. Syst. 2020, 33, 18661–18673. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Ma, F.; Zhang, Y.; Sun, X. Multimodal Sentiment Analysis with Preferential Fusion and Distance-Aware Contrastive Learning. In Proceedings of the 2023 IEEE International Conference on Multimedia and Expo, Brisbane, Australia, 10–14 July 2023; pp. 1367–1372. [Google Scholar] [CrossRef] [Scilit]
- Yang, Y.; Dong, X.; Qiang, Y. CLGSI: A Multimodal Sentiment Analysis Framework Based on Contrastive Learning Guided by Sentiment Intensity. In Proceedings of the Findings of the Association for Computational Linguistics: NAACL 2024; Association for Computational Linguistics: Stroudsburg, PA, USA, 2024; pp. 2099–2110. [Google Scholar] [CrossRef] [Scilit]
- Peyré, G.; Cuturi, M. Computational Optimal Transport. Found. Trends Mach. Learn. 2019, 11, 355–607. [Google Scholar] [CrossRef] [Scilit]
- Wang, S.; Stavrou, P.A.; Skoglund, M. Generalizations of Talagrand Inequality for Sinkhorn Distance Using Entropy Power Inequality. Entropy 2022, 24, 306. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Cuturi, M. Sinkhorn Distances: Lightspeed Computation of Optimal Transport. Adv. Neural Inf. Process. Syst. 2013, 26, 2292–2300. [Google Scholar]
- Tong, Q.; Kobayashi, K. Entropy-Regularized Optimal Transport on Multivariate Normal and q-Normal Distributions. Entropy 2021, 23, 302. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wang, J.; Wang, P.; Shafto, P. Efficient Discretization of Optimal Transport. Entropy 2023, 25, 839. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Chizat, L.; Peyré, G.; Schmitzer, B.; Vialard, F.X. Scaling Algorithms for Unbalanced Optimal Transport Problems. Math. Comput. 2018, 87, 2563–2609. [Google Scholar] [CrossRef] [Scilit]
- Chen, Z.; Lin, C.H.; Liu, R.; Xiao, J.; Dyer, E.L. Your Contrastive Learning Problem Is Secretly a Distribution Alignment Problem. arXiv 2025, arXiv:2502.20141. [Google Scholar] [CrossRef] [Scilit]
- Almousa, O.; Tashtoush, Y.; AlSobeh, A.; Zahariev, P.; Darwish, O. SiAraSent: From Features to Deep Transformers for Large-Scale Arabic Sentiment Analysis. Big Data Cogn. Comput. 2026, 10, 49. [Google Scholar] [CrossRef] [Scilit]
- Han, W.; Chen, H.; Poria, S. Improving Multimodal Fusion with Hierarchical Mutual Information Maximization for Multimodal Sentiment Analysis. In Proceedings of the 2021 Conference on Empirical Methods in Natural Language Processing; Association for Computational Linguistics: Stroudsburg, PA, USA, 2021; pp. 9180–9192. [Google Scholar] [CrossRef] [Scilit]
- Pham, H.; Liang, P.P.; Manzini, T.; Morency, L.P.; Póczos, B. Found in Translation: Learning Robust Joint Representations by Cyclic Translations Between Modalities. Proc. Aaai Conf. Artif. Intell. 2019, 33, 6892–6899. [Google Scholar] [CrossRef] [Scilit]
- Tang, J.; Li, K.; Jin, X.; Cichocki, A.; Zhao, Q.; Kong, W. CTFN: Hierarchical Learning for Multimodal Sentiment Analysis Using Coupled-Translation Fusion Network. In Proceedings of the 59th Annual Meeting of the Association for Computational Linguistics and the 11th International Joint Conference on Natural Language Processing; Association for Computational Linguistics: Stroudsburg, PA, USA, 2021; pp. 5301–5311. [Google Scholar] [CrossRef] [Scilit]
- Yu, W.; Xu, H.; Yuan, Z.; Wu, J. Learning Modality-Specific Representations with Self-Supervised Multi-Task Learning for Multimodal Sentiment Analysis. Proc. Aaai Conf. Artif. Intell. 2021, 35, 10790–10797. [Google Scholar] [CrossRef] [Scilit]
- Qian, C.; Xing, S.; Li, S.; Zhao, Y.; Tu, Z. DecAlign: Hierarchical Cross-Modal Alignment for Decoupled Multimodal Representation Learning. arXiv 2025, arXiv:2503.11892. [Google Scholar] [CrossRef] [Scilit]
- Li, X.; Zhang, X.; Miao, D.; Cheng, X.; Li, D.; Han, H.; Li, Z. Mixture of Disentangled Experts with Missing Modalities for Robust Multimodal Sentiment Analysis. Inf. Fusion 2026, 135, 104495. [Google Scholar] [CrossRef] [Scilit]
- Lin, R.; Hu, H. Multimodal Contrastive Learning via Uni-Modal Coding and Cross-Modal Prediction for Multimodal Sentiment Analysis. In Proceedings of the Findings of the Association for Computational Linguistics: EMNLP 2022; Association for Computational Linguistics: Stroudsburg, PA, USA, 2022; pp. 511–523. [Google Scholar] [CrossRef] [Scilit]
- Lin, Z.; Liang, B.; Long, Y.; Dang, Y.; Yang, M.; Zhang, M.; Xu, R. Modeling Intra- and Inter-Modal Relations: Hierarchical Graph Contrastive Learning for Multimodal Sentiment Analysis. In Proceedings of the 29th International Conference on Computational Linguistics; Association for Computational Linguistics: Stroudsburg, PA, USA, 2022; pp. 7124–7135. [Google Scholar]
- AlSobeh, A.; Khamaiseh, S.; Middendorf, D.; Dziubinski, J. CodeLLM-Auth: Multimodal Authorship Attribution and Verification via Supervised Contrastive Code Embeddings. In Proceedings of the 2026 IEEE 50th Annual Computers, Software, and Applications Conference (COMPSAC), Madrid, Spain, 7–10 July 2026; pp. 732–737. [Google Scholar] [CrossRef] [Scilit]
- Xie, Y.; Zhu, Z.; Lu, X.; Huang, Z.; Xiong, H. InfoEnh: Towards Multimodal Sentiment Analysis via Information Bottleneck Filter and Optimal Transport Alignment. In Proceedings of the 2024 Joint International Conference on Computational Linguistics, Language Resources and Evaluation (LREC-COLING 2024), Turin, Italy, 20–25 May 2024; pp. 9073–9083. [Google Scholar]
- Li, Y.; Xing, Y.; Lan, X.; Li, X.; Chen, H.; Jiang, D. AlignMamba: Enhancing Multimodal Mamba with Local and Global Cross-modal Alignment. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Nashville, TN, USA, 11–15 June 2025; pp. 24774–24784. [Google Scholar] [CrossRef] [Scilit]
- He, K.; Chen, B.; Ding, Y.; Li, F.; Teng, C.; Ji, D. PaSE: Prototype-aligned Calibration and Shapley-based Equilibrium for Multimodal Sentiment Analysis. Proc. Aaai Conf. Artif. Intell. 2026, 40, 30960–30968. [Google Scholar] [CrossRef] [Scilit]
- Wang, P.; Zhou, Q.; Wu, Y.; Chen, T.; Hu, J. DLF: Disentangled-Language-Focused Multimodal Sentiment Analysis. arXiv 2024, arXiv:2412.12225. [Google Scholar] [CrossRef] [Scilit]
- Quan, W.; Feng, Y.; Zhou, M.; Zhao, Y.; Wang, T.; Yan, D.M. TCAN: Text-oriented Cross Attention Network for Multimodal Sentiment Analysis. arXiv 2024, arXiv:2404.04545. [Google Scholar] [CrossRef] [Scilit]
- Lei, Y.; Yang, D.; Li, M.; Wang, S.; Chen, J.; Zhang, L. Text-oriented Modality Reinforcement Network for Multimodal Sentiment Analysis from Unaligned Multimodal Sequences. arXiv 2023, arXiv:2307.13205. [Google Scholar] [CrossRef] [Scilit]
- Zadeh, A.; Liang, P.P.; Mazumder, N.; Poria, S.; Cambria, E.; Morency, L.P. Memory Fusion Network for Multi-view Sequential Learning. Proc. Aaai Conf. Artif. Intell. 2018, 32, 5634–5641. [Google Scholar] [CrossRef] [Scilit]
- Zhi, Y.; Li, J.; Wang, H.; Chen, J. A Multimodal Sentiment Analysis Approach Based on Multiview Cross-Modal Fusion. IEEE Trans. Comput. Soc. Syst. 2026, 13, 136–151. [Google Scholar] [CrossRef] [Scilit]
- Wang, R.; Wang, Y.; Cambria, E.; Fan, X.; Yu, X.; Huang, Y.; E, X.; Zhu, X. Contrastive-Based Removal of Negative Information in Multimodal Emotion Analysis. Cogn. Comput. 2025, 17, 107. [Google Scholar] [CrossRef] [Scilit]
- Zhang, X.; Wei, W.; Zou, S. Modal Feature Optimization Network with Prompt for Multimodal Sentiment Analysis. In Proceedings of the 31st International Conference on Computational Linguistics; Association for Computational Linguistics: Stroudsburg, PA, USA, 2025; pp. 4611–4621. [Google Scholar]
- Du, Z.; Wang, Y.; Yang, X.; Im, S.K.; Wang, Z. MISA-GMC: An Enhanced Multimodal Sentiment Analysis Framework with Gated Fusion and Momentum Contrastive Modality Relationship Modeling. Mathematics 2026, 14, 115. [Google Scholar] [CrossRef] [Scilit]
- Lai, S.; Li, J.; Guo, G.; Hu, X.; Li, Y.; Tan, Y.; Song, Z.; Liu, Y.; Ren, Z.; Wang, C.; et al. Shared and Private Information Learning in Multimodal Sentiment Analysis with Deep Modal Alignment and Self-supervised Multi-Task Learning. In Proceedings of the 2024 International Joint Conference on Neural Networks (IJCNN), Yokohama, Japan, 30 June–5 July 2024; pp. 1–8. [Google Scholar] [CrossRef] [Scilit]
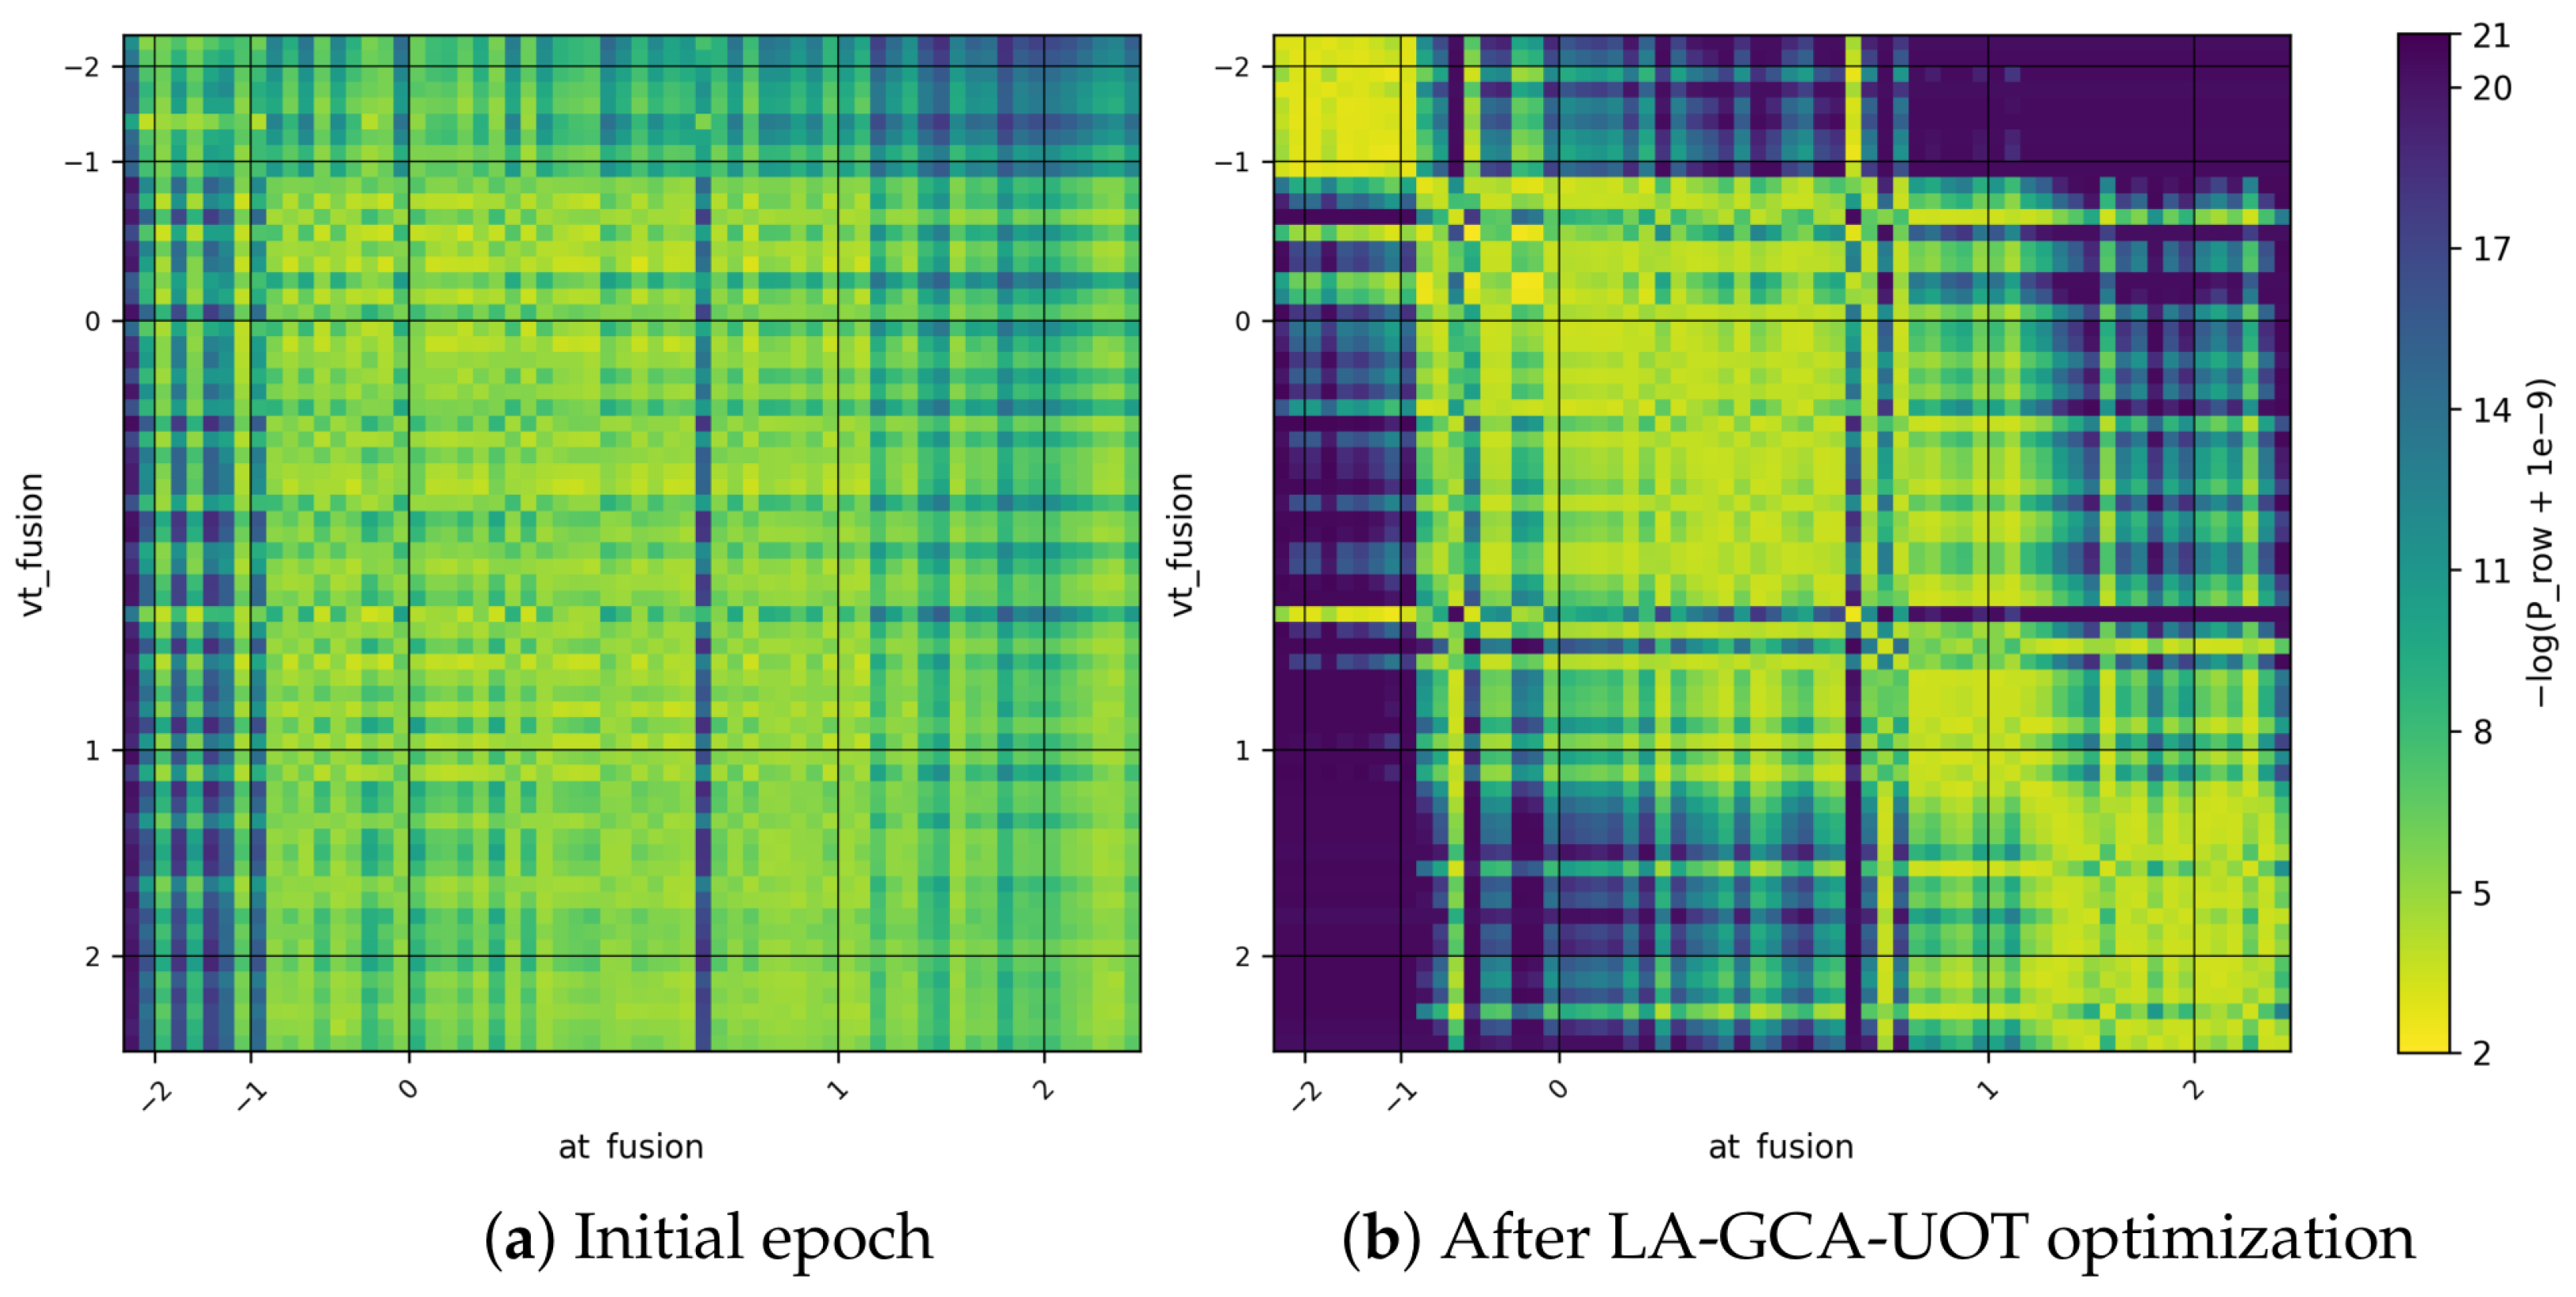
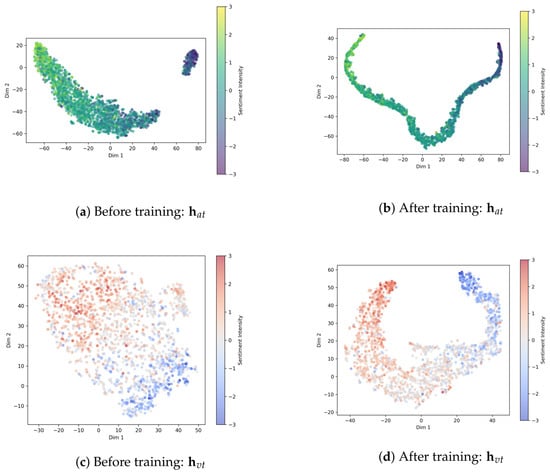
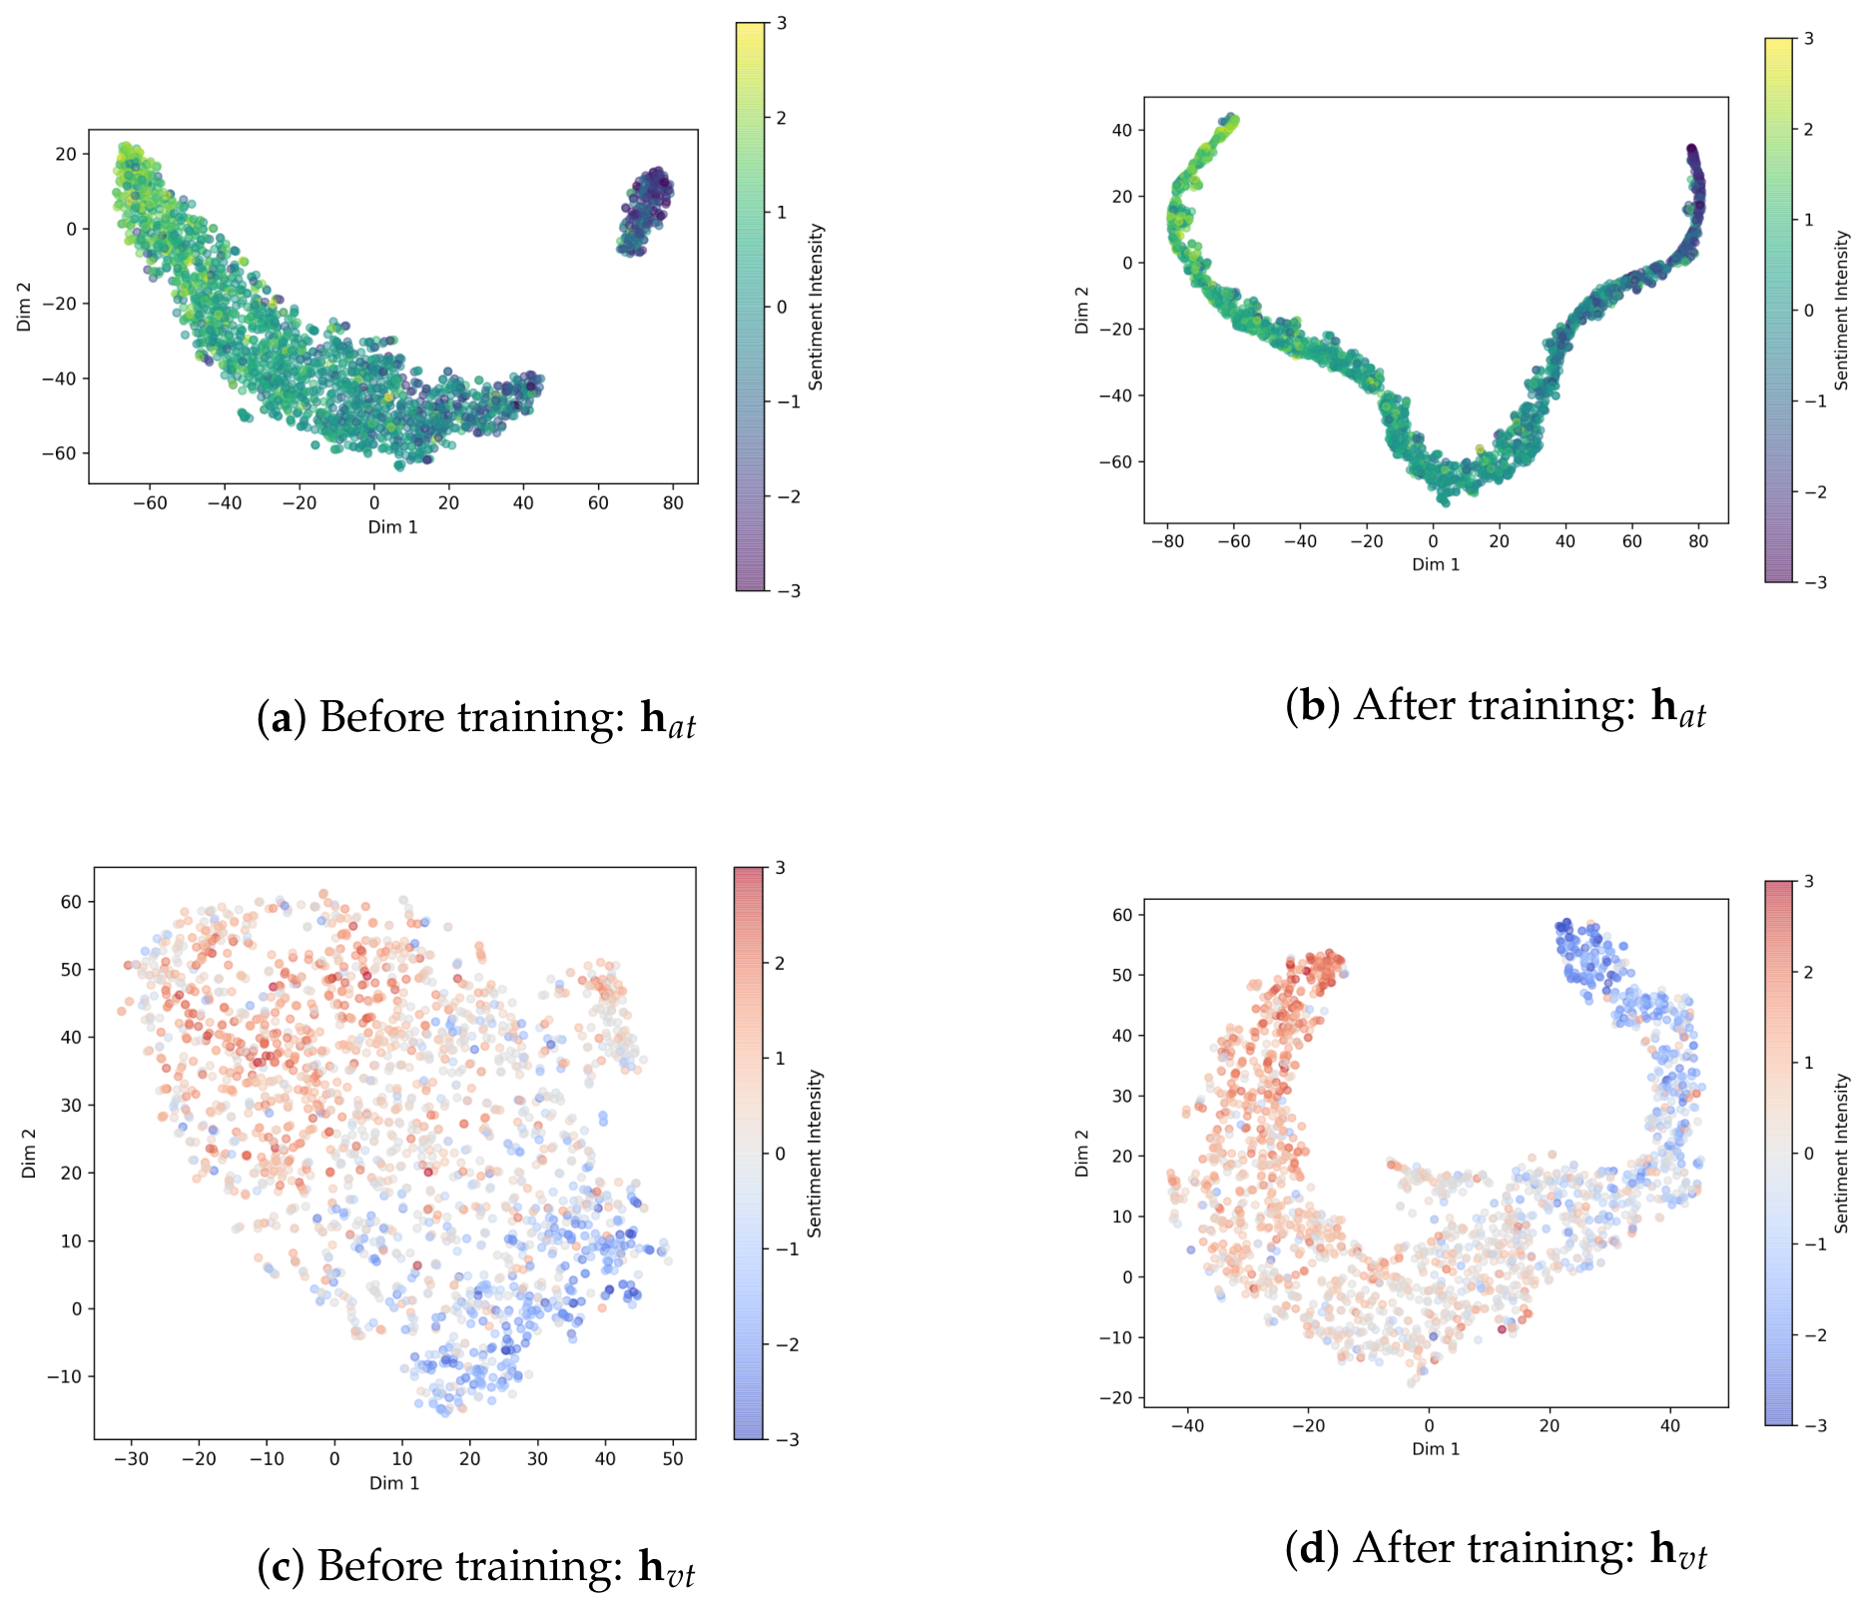

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.