


Abstract
This study presents a novel data-driven framework for developing airport-specific landing policies and procedures from historical successful-landing data. The proposed process, termed the Airport-Dependent Landing Procedure (ADLP), is motivated by the fact that airports rely on uniquely tailored approach charts reflecting local operational constraints and environmental conditions. While existing approach charts and landing procedures are primarily designed based on expert knowledge, safety margins, and regulatory conventions, the authors argue that data science and data mining techniques offer a complementary and empirically grounded methodology for extracting operationally meaningful structures directly from historical landing data. In this work, we construct a probabilistic three-dimensional environment from real-world aircraft approach trajectories, capturing spatiotemporal relationships under varying atmospheric conditions during approach. The proposed methodology integrates Adversarial Inverse Reinforcement Learning (AIRL) with Recurrent Proximal Policy Optimization (R-PPO) to establish a foundation for automated landing without pilot intervention. AIRL infers reward functions that are consistent with behaviors exhibited in prior successful landings. Subsequently, R-PPO is employed to learn control policies that satisfy safety constraints related to airspeed, sink rate, and runway alignment. Application of the proposed framework to real approach trajectories at Guam International Airport demonstrates the efficiency and effectiveness of the methodology.
1. Introduction
The landing phase remains one of the most demanding and safety-critical segments of all commercial flight operations. Statistical data from the International Air Transport Association (IATA) show that, in commercial aviation between 2005 and 2023, over half of all accidents occurred during the landing phase of flight, while takeoff accidents accounted for less than 10% of total accidents. This distribution highlights that, despite continuous improvements in overall safety and technology, landing remains one of the most accident-prone phases of flight [1]. It requires precise, continuous management of descent rate, airspeed, lateral alignment and energy state amid variable wind conditions. Other parameters, such as traffic constraints and airport geographical constraints usually add to the complexities involved. Despite significant advances in autopilot and flight-management systems, as well as “Instrument Landing Systems (ILS)”, human pilots still bear primary responsibility for the final approach and landing, where even small deviations can lead to abortion of the process and execution of “go-arounds” or, otherwise, runway excursions. On the other hand, with steadily increasing global air traffic and growing interest in higher levels of flight safety with even “single-pilot” operations as well as “crew-less” cargo aircraft; there is a pressing need for a sound and scientific approach to develop landing procedure and policies that could lead to control systems capable of replicating robust, expert-consistent landing performance which are based on the history of operational evidences at a given airport.
Traditional aircraft control system design relies heavily on aircraft analytical dynamic models. The process continues with linearized equations of motion and gain-scheduled controllers tuned for different aircraft conditions. Surprisingly enough, such tradition completely ignores the geographical airport characteristics and solely concentrates on the aircraft and its dynamical characteristics. Moreover, such a labor-intensive approach does not even guarantee any safety measures and still calls for many hours of flight-testing with different weights in different atmospheric disturbances, together with specifically tailored trainings at different airports. However, with new advances in Reinforcement Learning (RL) techniques, we are at a turning point in the development of a new class of control systems that have the ability to adjust themselves for different airport destinations. In this line of thought, in addition to the aircraft, the airport characteristics, as well as its approach charts, come into the process and play their roles from the beginning. Moreover, there are still no scientific processes for determining that a proposed approach chart for any airport is the best one possible. In fact, as long as such approach charts seem doable for ordinary pilots, they are approved. In this mechanism, it is the novice pilot who has to learn how to land at a given airport, and the burden is solely on the pilots to learn how to land at different airports. Nevertheless, the current work aims to enhance the situation and to lower pilot workload, while maintaining accepted level of safety. The idea is simple: with the help of data associated with successful previous landings, it is the aircraft that learns which trajectory to follow and how to land, not the pilot.
2. Safety Assurance and Certification Considerations
The integration of data-driven Reinforcement Learning (RL) policies into safety-critical aviation systems requires explicit consideration of verification, validation, and certification pathways. While the present work focuses on methodological development and trajectory-based reward inference, practical deployment must adhere to established aviation safety and regulatory frameworks.
2.1. Role of the Learned Policy Within Existing Architectures
The proposed framework is not intended to replace certified flight control laws or primary autopilot systems. Rather, it should be interpreted as a higher-level decision-support or guidance policy operating within pre-certified flight control envelopes. In such an architecture, low-level stability augmentation, envelope protection, and actuator command generation remain governed by certified control laws, while the learned policy produces intent-level guidance signals subject to supervisory constraints.
This hierarchical separation is essential for maintaining compliance with existing certification standards.
2.2. Verification of Learned Policies
The verification of a learned policy differs fundamentally from the verification of traditional rule-based or model-based control logic, requiring a multi-faceted approach to address the inherent uncertainties of Reinforcement Learning. This process begins with a rigorous state-space coverage analysis to ensure the training dataset sufficiently represents the operational domain, including both nominal and off-nominal conditions. To manage real-world uncertainties, the framework incorporates out-of-distribution (OOD) detection mechanisms that identify when the system encounters states not adequately represented during training. Safety is further reinforced through formal constraint enforcement, where hard operational limits—such as altitude deviation bounds, maximum bank angle, and descent rate constraints—are embedded independently of the learned reward function to guarantee adherence to safety envelopes. These measures are validated through extensive Monte Carlo stress testing, involving large-scale stochastic simulations to evaluate robustness under varied environmental conditions. In the present framework, the use of discrete action abstraction and an empirical transition model facilitates an exhaustive evaluation across the discretized state–action domain, enabling a level of systematic safety analysis that would be significantly more complex under continuous-control formulations.
2.3. Validation Against Operational Standards
Validation of the learned policy must be conducted through a multi-level framework to ensure full alignment with rigorous aviation requirements. At the trajectory level, generated flight paths are evaluated against expert demonstrations using specific stability criteria, such as glide path adherence, lateral deviation thresholds, and stabilized approach markers. This is supplemented by procedure compliance validation, which confirms that the policy’s behaviors conform to published instrument approach procedures and mandatory separation requirements. Furthermore, performance envelope validation is required to verify that the policy does not induce control commands leading to excursions beyond certified flight envelopes. While the proposed framework implicitly captures compliance characteristics by learning from real-world operational data, this inherent imitation is not a substitute for formal proof; therefore, explicit verification against procedural and safety constraints remains a mandatory prerequisite for any operational deployment.
2.4. Certification Pathways
Current aviation certification standards, primarily DO-178C for airborne software and ARP4754A for system development, are fundamentally structured around deterministic, traceable logic and exhaustive structural coverage. Integrating data-driven RL policies requires a shift toward modern “learning assurance” frameworks, as outlined in emerging regulatory guidance such as the EASA AI Roadmap and the FAA’s autonomous system initiatives. A viable certification pathway involves strictly defining the Operational Design Domain (ODD) to bound the environmental conditions under which the policy remains valid, while treating the post-training model parameters as configuration-controlled, frozen software. Furthermore, robustness can be enhanced by adopting a multi-tiered assurance approach (often referred to as a W-shaped development process), which supplements traditional V-model verification with rigorous data quality analysis and runtime monitoring. Ultimately, a practical deployment strategy positions the learned policy as an advisory or augmentation layer within a monitor–checker architecture, where a pre-certified, deterministic safety governor maintains the authority to override AI-generated signals, thereby ensuring the system’s integrity remains compliant with established safety envelopes.
3. Learning Mechanisms of Learning-Capable Aircraft
In this work, we use Inverse Reinforcement Learning (IRL), and particularly its adversarial variant (AIRL), to address existing challenges to extract landing policies directly from previous successful landing data, instead of “Airport Approach Charts”. The process recovers suitable reward functions directly from previous expert demonstrations, eliminating the need for manual reward manipulations. When combined with modern policy optimization methods, such as Proximal Policy Optimization (PPO), AIRL enables the training of policies that closely mimic previous experts’ behavior. It has to be noted that unlike most prior works that rely on simulated environments for learning, we explicitly use actual aircraft trajectories, so there are neither simplified dynamics involved nor any simplifications that might compromise the safety of the aircraft and its passengers.
The rest of the manuscript describes the framework of the so-called “Policy Inference from Logged Operational Trajectories (PILOT)” in the following three steps:
- Step 1 describes how we can collect and prepare the relevant data for a specific flight case, such as ADS-B data during the approach to a specific airport.
- Step 2 describes the learning process to form a robust, expert-consistent, 3D controller exclusively from real-world data associated with Step (1).
- Step 3 describes how the process could be fine-tuned for a specific airport, which in this study is International Airport (PGUM).
With proper data (For this work, 1039 successful approaches), we construct a probabilistic Markov decision process (MDP) that captures empirical spatiotemporal relationships in properly selected aircraft states. Different case-studies reveal that during the approach phase of the flight, aircraft altitude, lateral deviation, and energy state are the minimum necessary. Of course, other parameters could be added to the list, as needed. AIRL process is then applied to infer a reward function consistent with observed aircraft behavioral states, followed by recurrent PPO (R-PPO) training of an LSTM-based policy that aims to produce stable, coherent commands for the autopilot during approach.
In this approach, we are using all the data associated with “Successful flight conditions”. We, obviously, expect safety and realism to be naturally enforced in all critically selected states. The primary contributions of this work are:
- A new probabilistic model based on real-world data to extract policies without mathematical models.
- Extraction of applied reward functions directly from the history of operation to feed into R-PPO, eliminating the need for trial-and-error in the process of reward adjustment.
- Provision of implicit robustness and stability based on experts in the field’s historical data.
- Provision of a built-in validation process in the model, with robustness to initial-state variations, and guaranteed valid terminal conditions.
Based on the mentioned contributions, this work paves the way to developing a new class of control system that has the ability to mimic landing policies suitable for both manned and unmanned aircraft systems.
4. Literature Review
Adversarial Inverse Reinforcement Learning (AIRL) has become a central method for extracting reward functions from expert demonstrations using an adversarial discriminator–generator structure. The foundational work of Fu et al. [2] introduced AIRL as a robust alternative to traditional IRL, demonstrating improved reward transferability and policy generalization in continuous-control domains. This triggered a series of studies aimed at improving reward stability, scalability, and sample efficiency.
Several methodological extensions build on this foundation. Model-based variants such as MAIRL [3] introduced a self-attention dynamics model to reduce optimization variance, while option-based approaches such as oIRL [4] improved reward disentanglement through temporally extended actions. Off-policy AIRL [5] addressed the high sample cost of the original on-policy formulation, and generative extensions combining AIRL with DDPG [6] reduced training time through deterministic sampling. Hybrid AIRL (HAIRL) [7] incorporated curiosity-driven exploration to mitigate AIRL’s tendency toward premature exploration saturation.
A major application area for AIRL is sequential decision-making. In autonomous driving, several augmented AIRL frameworks [8,9] incorporated semantic features to improve learning stability and decision accuracy in interactive traffic settings, consistently outperforming GAIL and Reinforcement Learning baselines. Beyond single-agent domains, multi-agent and adversarial extensions such as MA-AIRL [10] and I-IRL [11] expanded AIRL to strategy recovery in Markov games and adversarial environments. More recent work has addressed long-horizon challenges: hierarchical critics and subtask decompositions in H-AIRL [12] and SC-AIRL [13] improved credit assignment and exploration in complex robotic-manipulation problems.
Overall, these studies highlight AIRL’s strengths in reward interpretability, robustness, and behavioral fidelity. However, the existing literature exhibits several limitations. AIRL research remains heavily dependent on simulated environments and rarely incorporates high-dimensional, physics-informed state representations.
Building on the advancements in Adversarial Inverse Reinforcement Learning (AIRL) for robust reward recovery from expert demonstrations, broader applications of Deep Reinforcement Learning (DRL) and Deep Imitation Learning (DIL) have extended these techniques to safety-critical domains.
Deep Reinforcement Learning (DRL) and Deep Imitation Learning (DIL) have emerged as leading paradigms for autonomous control in complex, safety-critical domains such as autonomous driving and mobile robotics [14,15,16,17]. These approaches have been successfully extended to Unmanned Aerial Vehicles (UAVs), enabling high-performance autonomous flight—including human-champion-level performance in real-world drone racing [18,19]. Notable applications include continuous-action obstacle avoidance [20], wind-aware navigation procedure optimization [14], and airport traffic management [21]. Algorithms such as Proximal Policy Optimization (PPO), Deep Deterministic Policy Gradient (DDPG), and modular or curriculum-based training have proven effective for motion planning and control in dynamic, uncertain environments [18,22,23].
Despite these advances, the “sim-to-real” gap remains a fundamental obstacle: most DRL methods perform well in simulation but degrade significantly in physical deployment due to unmodeled dynamics, sensor noise, and environmental variability [24,25]. Domain randomization and high-fidelity simulators offer partial solutions [24], yet direct learning from real-world data is increasingly recognized as a more robust path forward. Offline Reinforcement Learning, which trains solely on static datasets without online interaction, has gained prominence for applications where real-time exploration is expensive or hazardous [26].
A parallel challenge in applying RL to aircraft landing is the difficulty of manually designing reward functions that capture the subtle, multi-objective trade-offs expert pilots employ. Inverse Reinforcement Learning (IRL), particularly Adversarial IRL (AIRL), resolves this by inferring reward functions directly from expert demonstrations, thereby producing human-like policies without explicit reward engineering [27]. Combining AIRL with recurrent policy optimization (e.g., PPO with LSTM architectures) further supports stable, long-horizon decision-making required for extended flight segments.
Safety and certifiability are non-negotiable in aviation. Recent surveys stress the need for constrained learning, formal safety guarantees, and explicit enforcement of operational envelopes [20,28]. Terminal constraints on critical variables (airspeed, sink rate, alignment) and rigorous containment analysis within observed state distributions directly address these requirements.
The PILOT framework advances this body of work by learning robust, pilot-like landing policies exclusively from 1039 real-world ADS-B approach trajectories collected at Antonio B. Won Pat International Airport (PGUM), Guam, across diverse meteorological conditions and aircraft types. By constructing an empirical probabilistic Markov decision process, employing AIRL to recover pilot-consistent rewards, and training a recurrent PPO policy with explicit safety constraints, PILOT eliminates both hand-crafted rewards and dependence on analytic flight dynamics models. Validation demonstrates close statistical agreement with expert trajectories and physical plausibility up to the vicinity of the runway. This fully offline, data-anchored approach directly mitigates the sim-to-real gap and establishes the feasibility of deriving versatile, expert-level guidance for both manned and future unmanned aircraft using only operational surveillance data.
5. Dataset and Preprocessing
The flight dataset used in this study focuses on approach and landing operations at Guam International Airport (PGUM). The details of the dataset are shown in Table 1.
Table 1.
Flight dataset summary for Guam International Airport (PGUM).
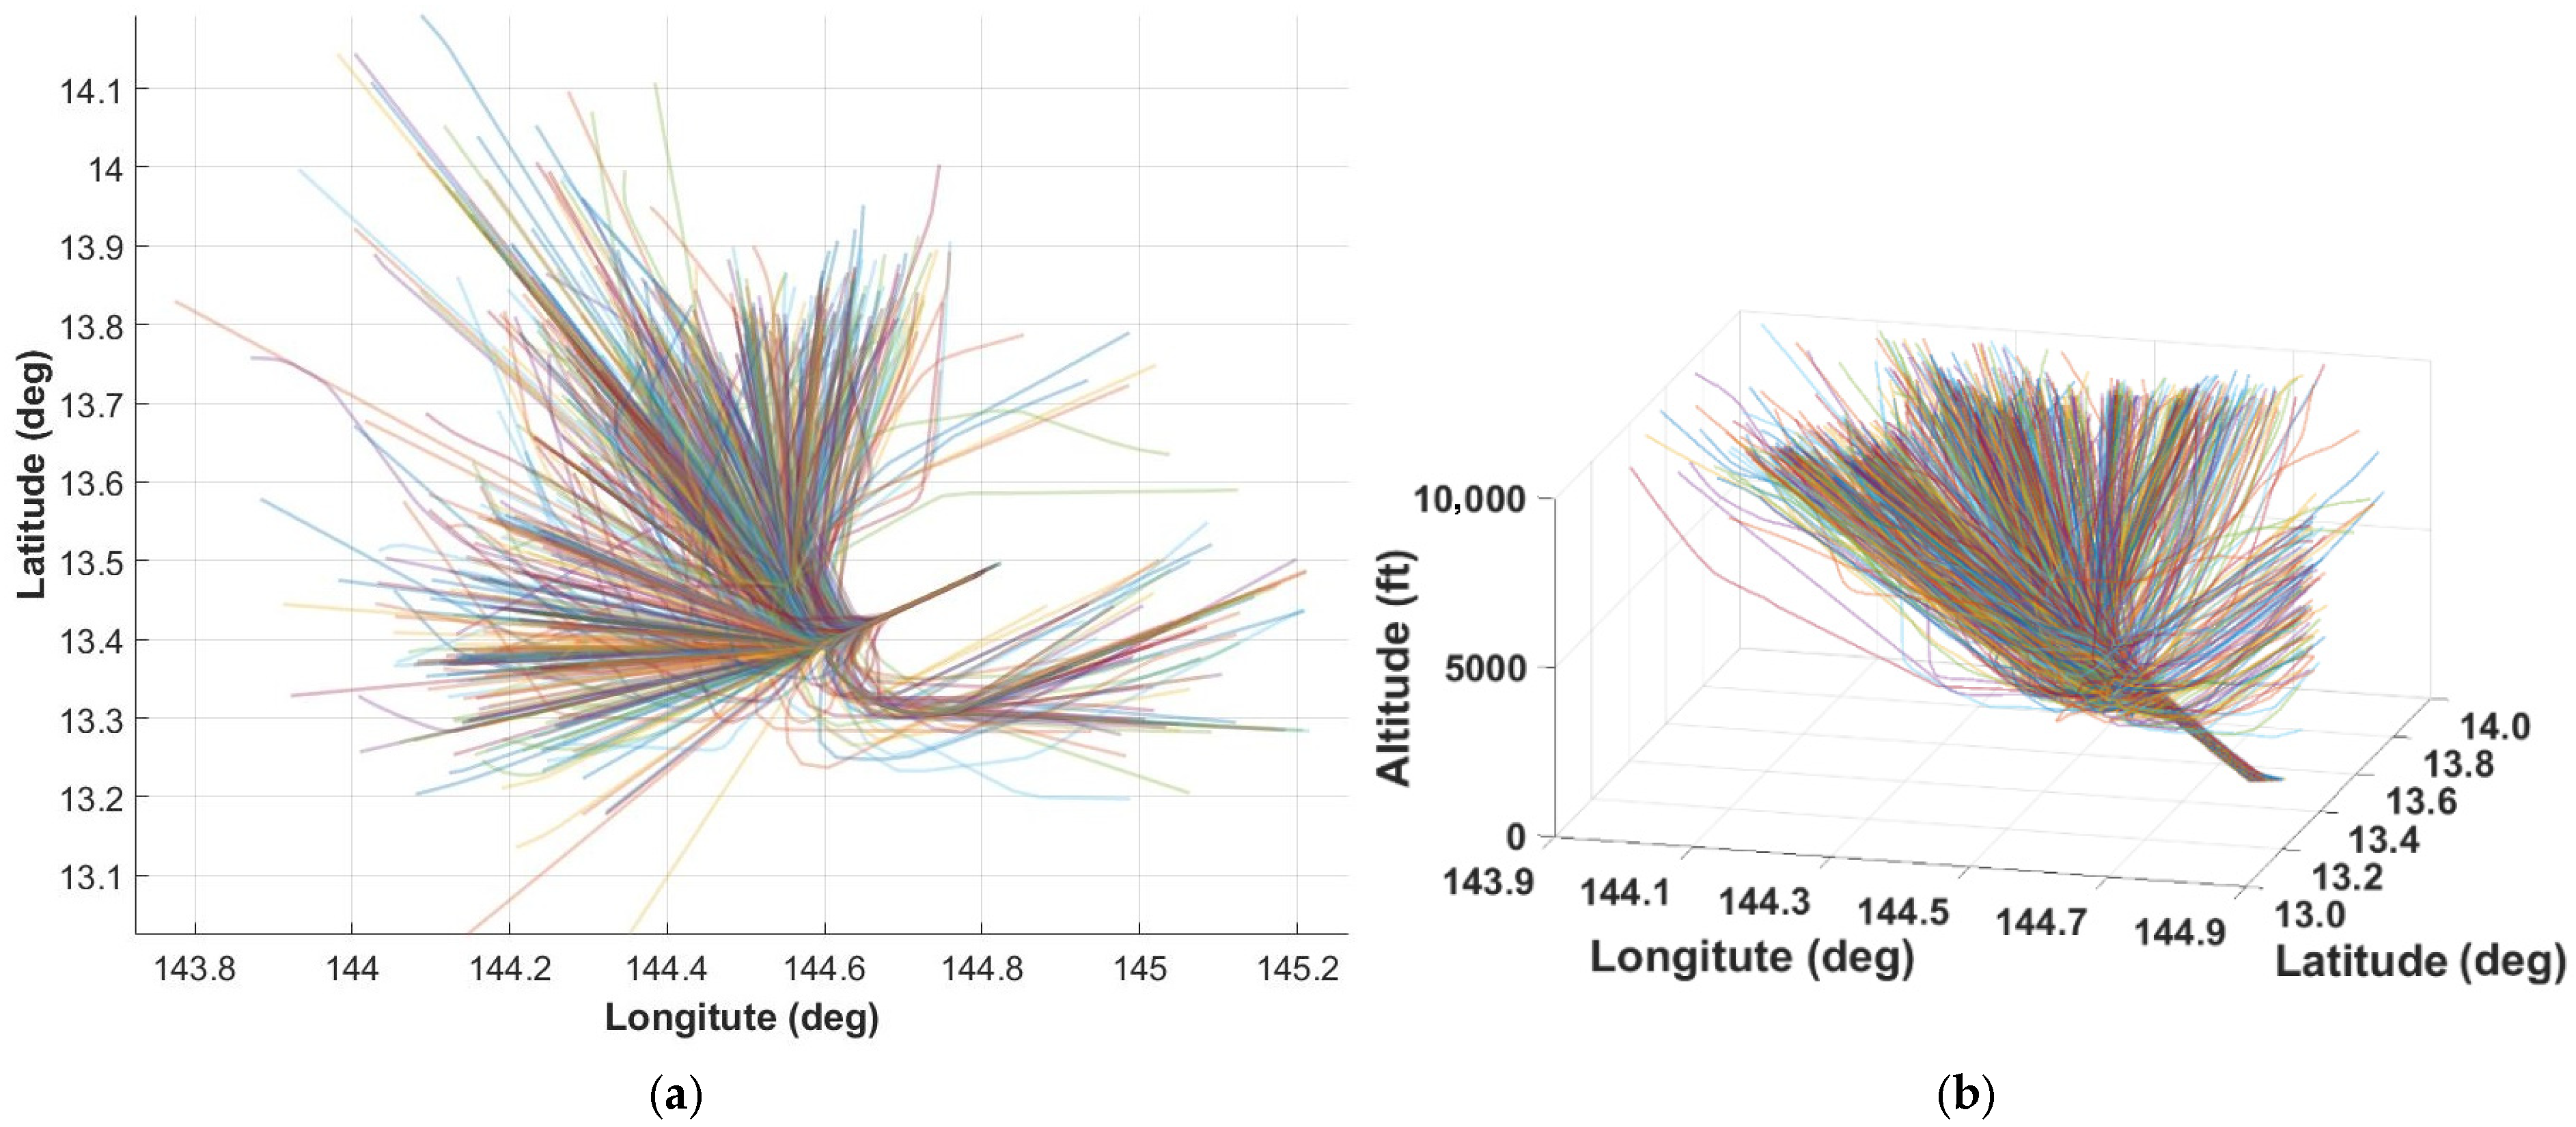
A total of 1039 flight trajectories from 142 individual aircraft were collected, covering twelve major aircraft types, including the Airbus A321 and A330, as well as the Boeing 737, 757, 767, 777, and 787 series. All trajectories are related to the PGUM; therefore, the present study evaluates generalization across aircraft types within a single-airport operational context, not across airport geometries or procedures. These flights represent a diverse range of operational conditions and configurations typical of commercial approach procedures. The corresponding 2D and 3D views are shown in Figure 1.
Figure 1.
Approaches to Guam Airport, located at 13.48° N, 144.80° E: (a) 2D view; (b) 3D view.
Each trajectory contains 1 Hz measurements recorded during the terminal descent phase. All records were filtered to remove incomplete, duplicated, or physically inconsistent samples. Minor temporal gaps were filled using linear interpolation. The resulting dataset provides the foundation for constructing the probabilistic flight environment.
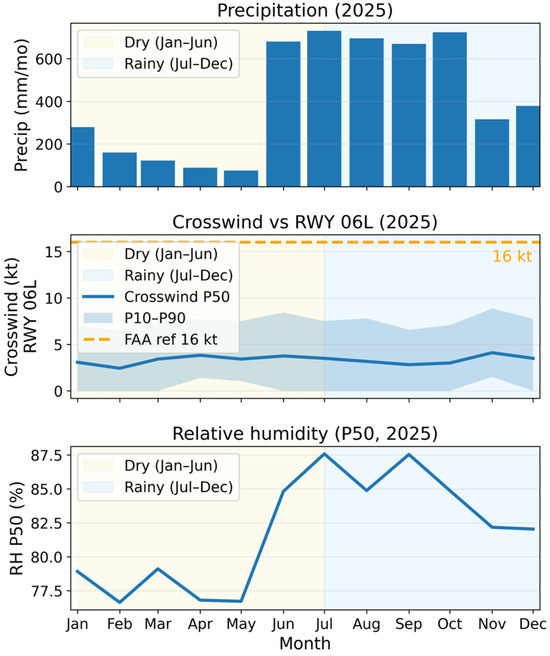
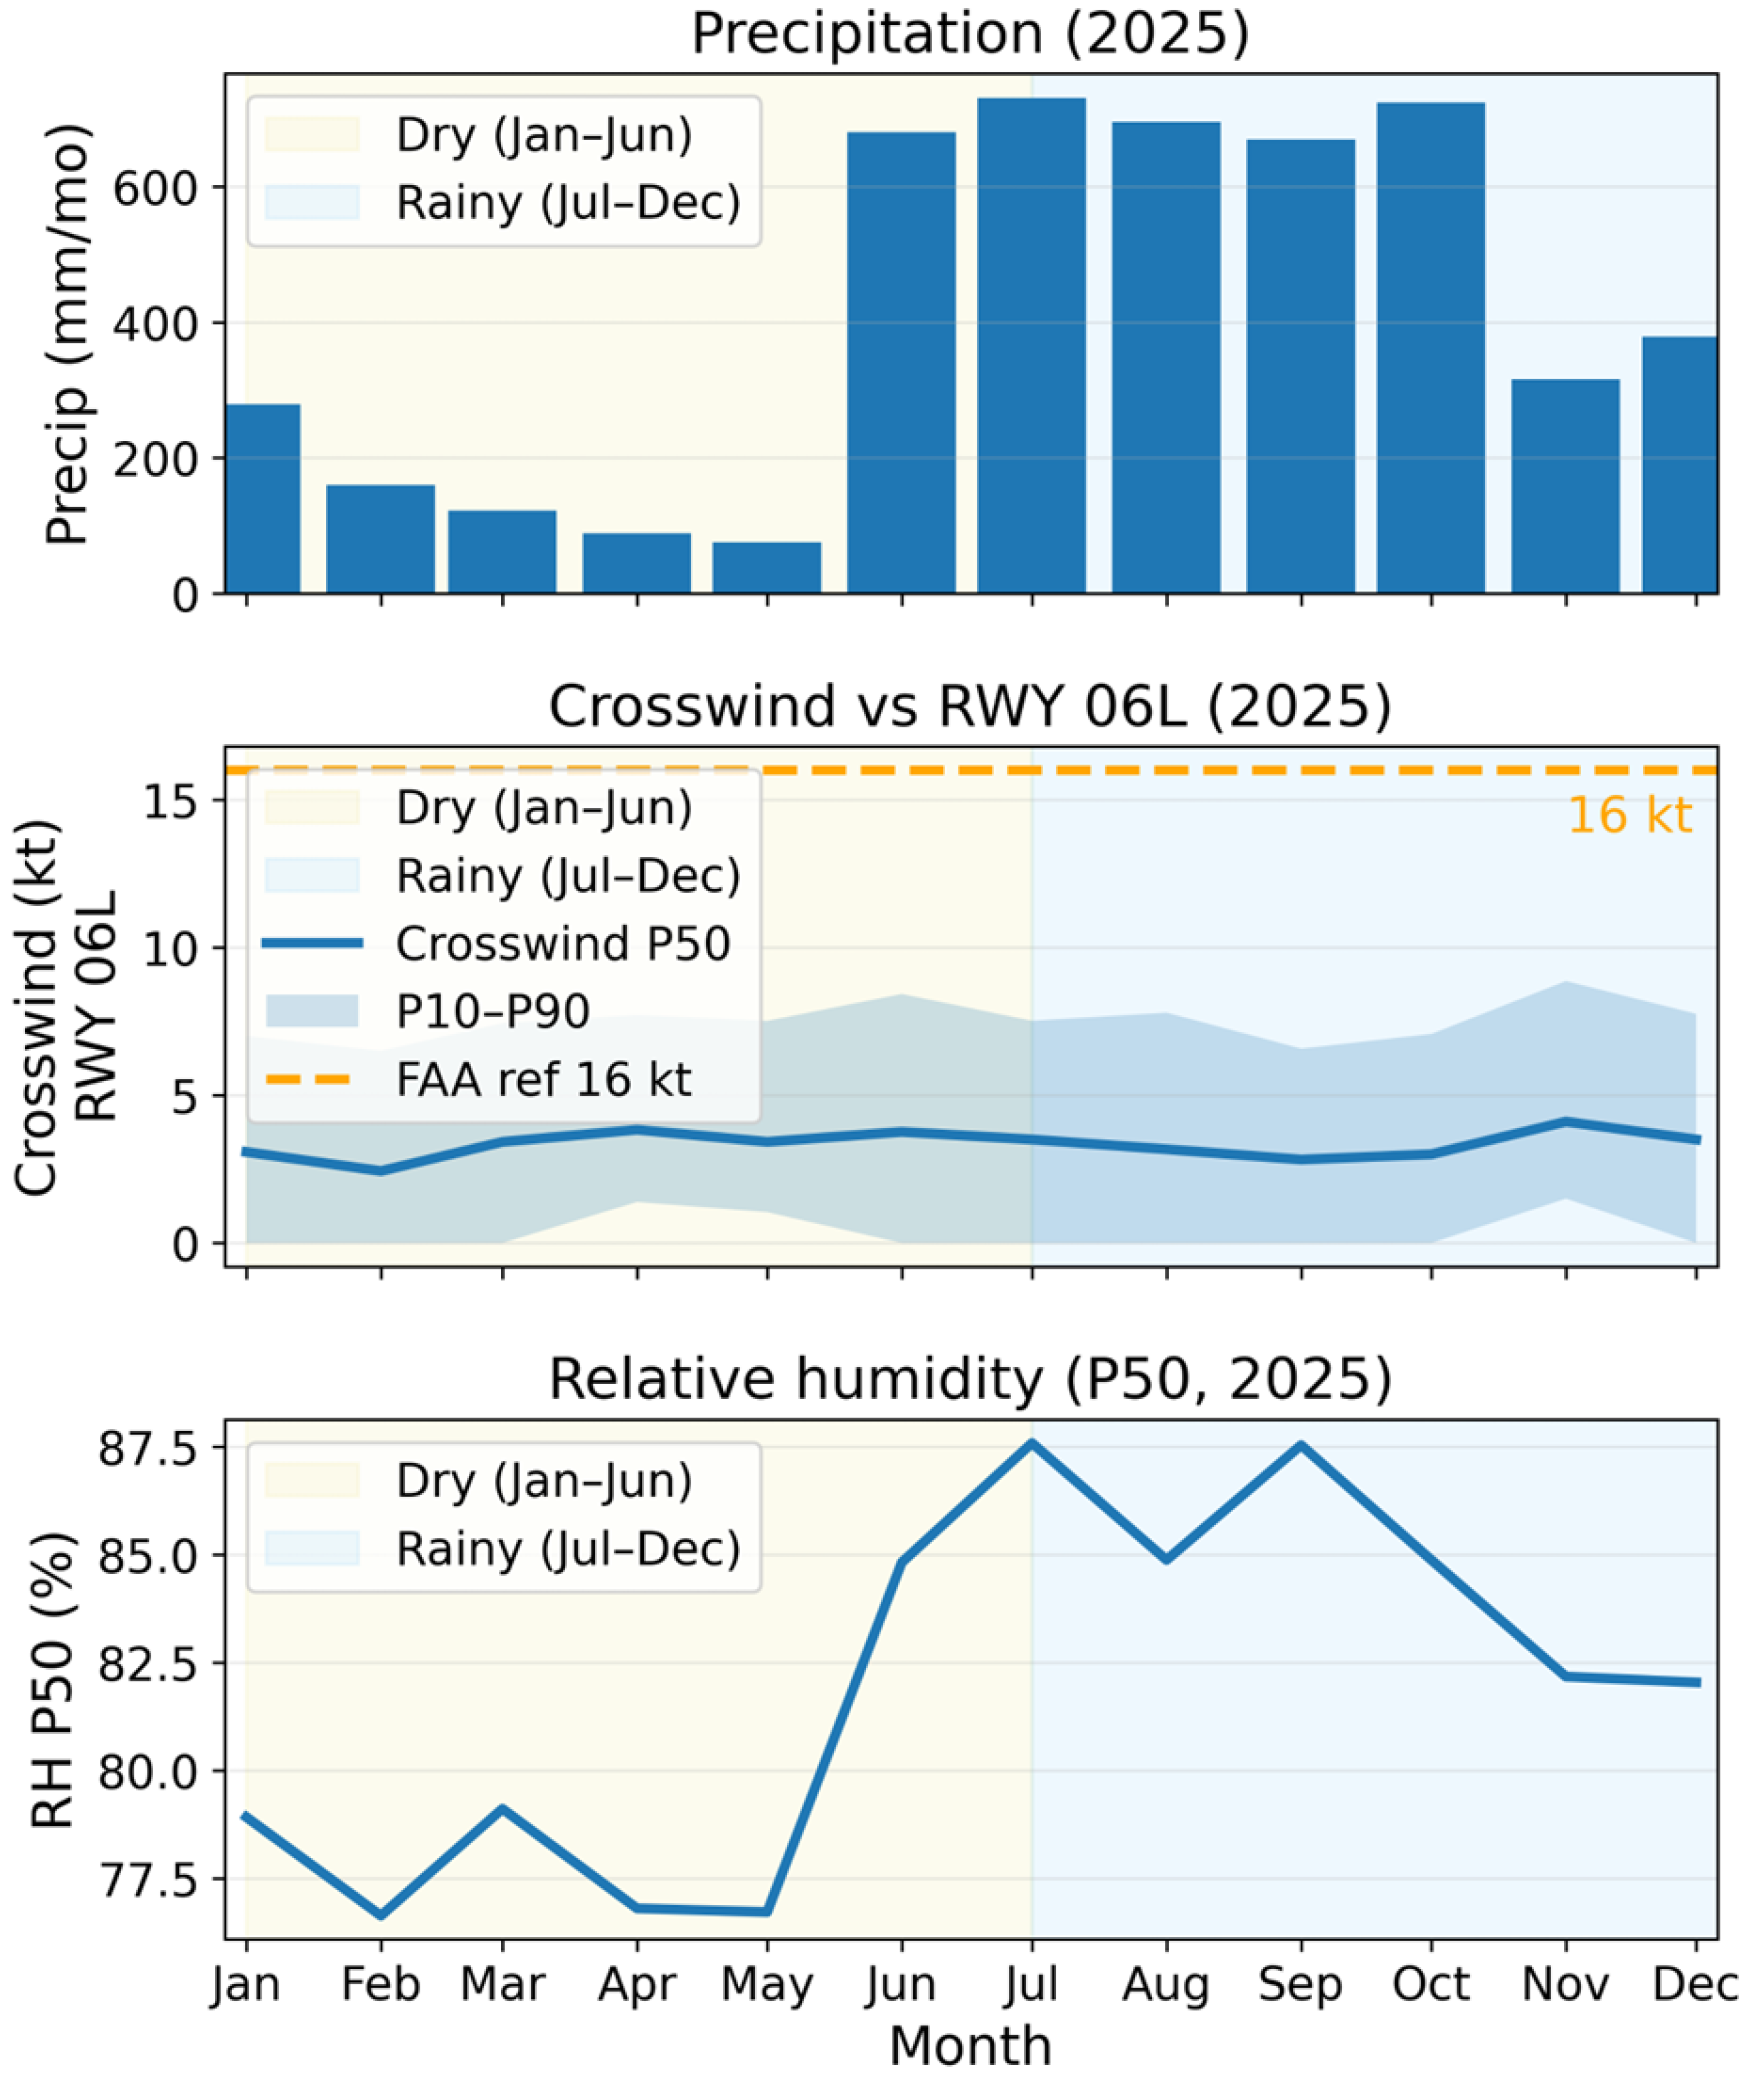
Meteorological variability during the 2025 data-collection period at Guam International Airport (PGUM) was characterized using routine aerodrome weather reports (METAR) [29]. METAR observations for PGUM were retrieved from the Iowa Environmental Mesonet (IEM) ASOS/AWOS/METAR archive using the asos.py interface [30]. The METAR wind fields (direction and speed) were used to compute the crosswind component relative to RWY 06L, and temperature/dew-point observations were used to compute relative humidity [29]. For visualization, months were grouped into a dry season (January–June) and a rainy season (July–December), consistent with climatological descriptions for Guam [31]. Figure 2 provides a compact summary for 2025, including monthly precipitation totals, the monthly distribution (P10–P50–P90) of the RWY 06L crosswind component, and monthly median relative humidity. The dashed 16 kt line in the crosswind panel denotes the FAA airport design allowable-crosswind component used in runway wind coverage analyses, included here as a design reference rather than an aircraft operational landing limit [32].
Figure 2.
PGUM meteorological summary for 2025 (RWY 06L). Monthly precipitation totals, RWY 06L crosswind component (P10–P50–P90), and monthly median relative humidity for PGUM in 2025, with dry (Jan–Jun) and rainy (Jul–Dec) seasons indicated.
6. State–Action–Environment Modeling
6.1. State Representation
The aircraft state is modeled using a nine-dimensional vector containing geometric, kinematic, and energetic quantities relevant to approach and landing, as defined in (1):
These features represent distance and alignment relative to the runway, vertical profile, heading behavior, and total energy state. A detailed list of all variables and their physical meaning is provided in Table 2.
Table 2.
State variables and final discretization widths.
6.2. Robust Normalization and Grid Construction
To ensure consistent scaling and avoid the influence of outliers, robust lower and upper bounds for each state variable were extracted directly from the flight dataset using quantile-based clipping. These bounds define the operational envelope used throughout the learning process.
A uniform discretization grid was then constructed: a single bin width per dimension was computed using the Freedman–Diaconis [33] rule and constrained within physically meaningful limits (e.g., minimum altitude resolution, maximum allowable slope step).
The bin width h is defined in (2) as follows:
where IQR(x) is the interquartile range of the data and n is the sample size. This rule provides a data-adaptive, outlier-robust discretization scale, ensuring the grid is neither too coarse nor too fine before applying domain-specific constraints.
These bin widths were held constant across the full domain and are summarized in Table 2.
This procedure yields a stable and interpretable partition of the continuous state space, forming the basis for constructing the empirical transition model and extracting expert demonstrations.
6.3. Demonstration Extraction
The flight dataset was split into training, validation, and test subsets. Each trajectory was converted into a sequence of expert demonstrations by labeling pilot control commands (actions) as vertical (climb/level/descend) and lateral (left/straight/right) based on changes in altitude and heading rate. These labeled demonstrations serve as the supervisory signal for reward learning and policy optimization.
6.4. Action Space and Expert Labeling
The control space is discretized into nine primitive actions, representing the Cartesian combination of vertical and lateral intentions as given in (3):
Actions are labeled from flight data by analyzing local altitude and heading changes. A dynamic vertical threshold is considered as in (4):
And a turn threshold, , is used to classify each time step into one of the nine action categories. This results in discrete state–action pairs suitable for transition modeling.
6.5. Action Space Design
The action space is defined as the Cartesian product of three vertical intents and three lateral intents, yielding nine discrete high-level actions. This formulation abstracts control at the level of pilot intent rather than actuator commands, consistent with the information content of 1 Hz ADS-B data, which captures kinematic trends (e.g., altitude rate, heading change) rather than continuous control inputs.
The 3 × 3 structure enables coordinated vertical–lateral corrections within a single decision step, which is essential for modeling stabilized approach behavior. Simpler formulations that restrict actions to single-axis adjustments cannot represent simultaneous corrections and tend to produce sequential or oscillatory motion patterns.
Statistical Considerations in an Empirical MDP
The environment is constructed empirically from observed state–action–next-state frequencies, without imposing a parametric flight dynamics model. In such a tabular MDP, increasing action cardinality directly reduces the number of samples per state–action pair.
Finer discretizations partition the dataset into a larger number of bins, leading to sparse transition statistics. This sparsity degrades the reliability of estimated transition probabilities, increases variance in AIRL reward inference, and destabilizes PPO due to noisy gradient estimates. Conversely, overly coarse discretization reduces behavioral expressiveness and fails to capture coordinated corrective maneuvers.
The selected nine-action configuration, therefore, reflects a principled trade-off between behavioral fidelity and statistical robustness under the available dataset size and sampling frequency.
7. Training Methodology
7.1. Environment and Demonstration Preparation
The training environment is a data-derived Markov decision process formed from two empirical components: the transition kernel , obtained from state–action frequency counts, and the conditional feature statistics , which summarize the continuous flight variables associated with each discrete transition. States correspond to quantized combinations of flight parameters, and next-state samples are drawn directly from observed transitions in the dataset. Expert demonstrations extracted from 1 Hz flight recordings provide sequences of 9-dimensional states and discrete pilot actions , formatted for the AIRL algorithm. The environment itself is reward-free; the learned reward is applied later through a wrapper that evaluates it online using the trained reward network.
7.2. Learning Framework and Model Architecture
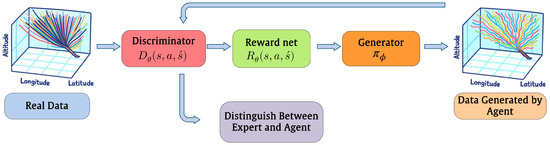
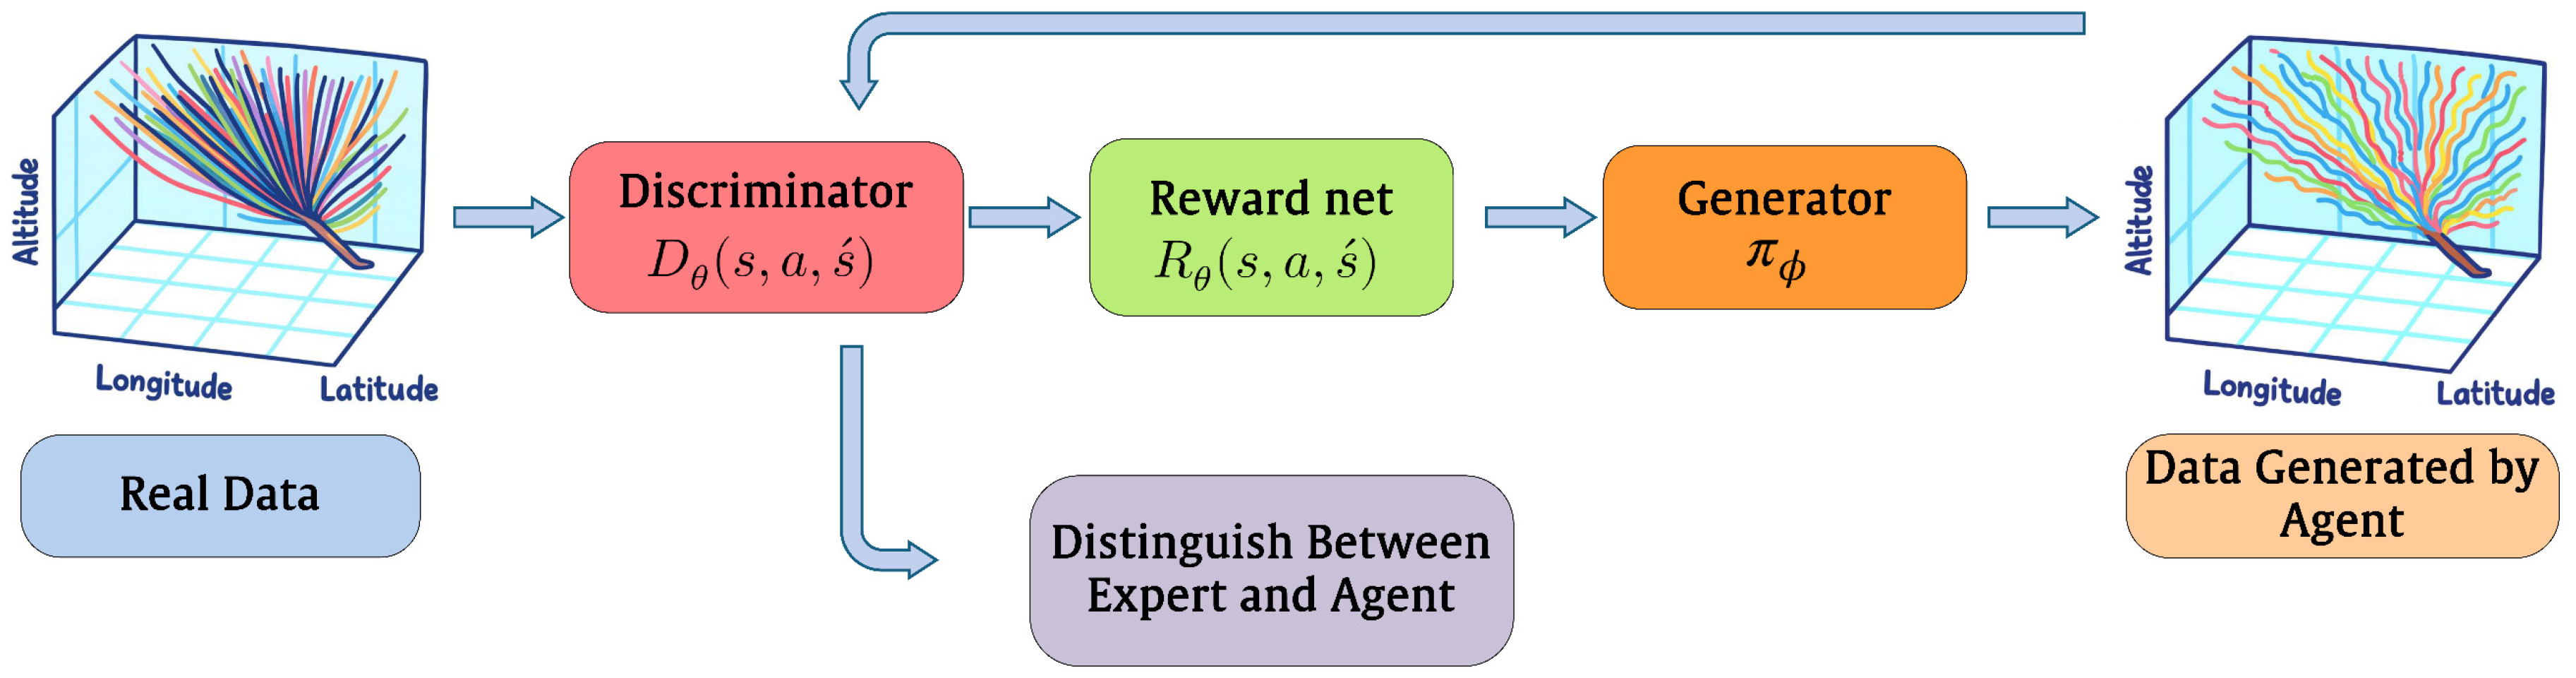
The proposed model is trained using a unified two-stage learning framework that integrates Adversarial Inverse Reinforcement Learning (AIRL) for reward inference with a Recurrent Proximal Policy Optimization (R-PPO) agent for policy optimization. This architecture enables the system to first recover a latent reward function directly from expert flight demonstrations and subsequently learn a stable closed-loop control policy capable of reproducing pilot-like behavior across extended approach segments. In the first stage, AIRL is used to infer an intrinsic reward signal that best explains the demonstrated trajectories. AIRL formulates the problem as an adversarial game between a discriminator , which attempts to distinguish expert transitions from those generated by a provisional policy, and a generator that represents a PPO agent acting within a data-driven Markov decision process. Following the original AIRL formulation by [2], the discriminator models the density ratio between expert and policy-generated transitions via Equation (5):
where is an energy-based reward-shaping function. The intrinsic reward is then recovered through the canonical AIRL transformation as given in (6):
Which yields a scalar reward consistent with maximum-entropy Inverse Reinforcement Learning and is theoretically guaranteed to recover a reward that is invariant under potential-based shaping, thereby preserving the optimal policy [34]. The discriminator is implemented as a multilayer perceptron that receives the concatenated transition vector , normalized using running statistics to ensure numerical stability. The network consists of three fully connected layers with 256, 128, and 64 units with Leaky-ReLU nonlinearities, followed by a sigmoid output that provides the probability of a transition being expert-generated. During AIRL training, the discriminator and generator are optimized alternately: the discriminator is updated to improve its ability to classify transitions, while the PPO generator is updated to maximize the inferred reward function. We used discriminator indistinguishability (accuracy near 0.5) as a heuristic convergence signal, and additionally monitored policy performance metrics to avoid premature stopping due to discriminator underfitting. Figure 3 illustrates the AIRL stage.
Figure 3.
AIRL Stage.
After convergence of the AIRL stage, the learned reward function is fixed and used to train the final controller through Recurrent PPO. The policy network adopts an MlpLstm architecture composed of two 128-unit feed-forward layers followed by a 256-unit LSTM module. The actor head predicts logits over nine discrete control primitives representing vertical and lateral intent classes (climb/level/descend × left/straight/right) inferred from observed state changes., while the critic estimates the value function . The temporal recurrence in the LSTM enables the agent to integrate sequential information, capture flow-dependent structure in aircraft dynamics, and maintain stable control behavior throughout the approach path. Policy optimization follows the clipped surrogate objective introduced by [35] as shown in (7),
where is the probability ratio defined in (8);
and denotes the advantage estimate.
Both AIRL and PPO are trained within a data-derived environment constructed from empirical flight trajectories. The continuous state space is discretized using a distribution-adaptive scheme. This rule provides a statistically robust, outlier-tolerant discretization that is subsequently constrained by flight dynamics-specific limits such as minimum altitude resolution and maximum allowable slope variation. For each dimension in the state representation, empirical transition counts are accumulated to construct a tabular transition model , ensuring that the environment captures the stochastic variations present in expert behavior. During both AIRL and PPO training, the agent interacts exclusively with this data-driven MDP, guaranteeing that policy learning remains grounded in the distributional structure of real trajectories rather than relying on analytically simplified models.
This integrated framework allows the controller to learn from the implicit decision-making patterns encoded in pilot demonstrations, recover a reward function that reflects expert intent, and synthesize a recurrent policy that generalizes this behavior across the full landing approach envelope.
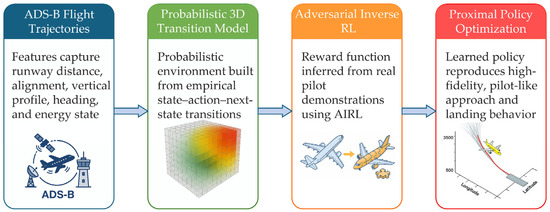
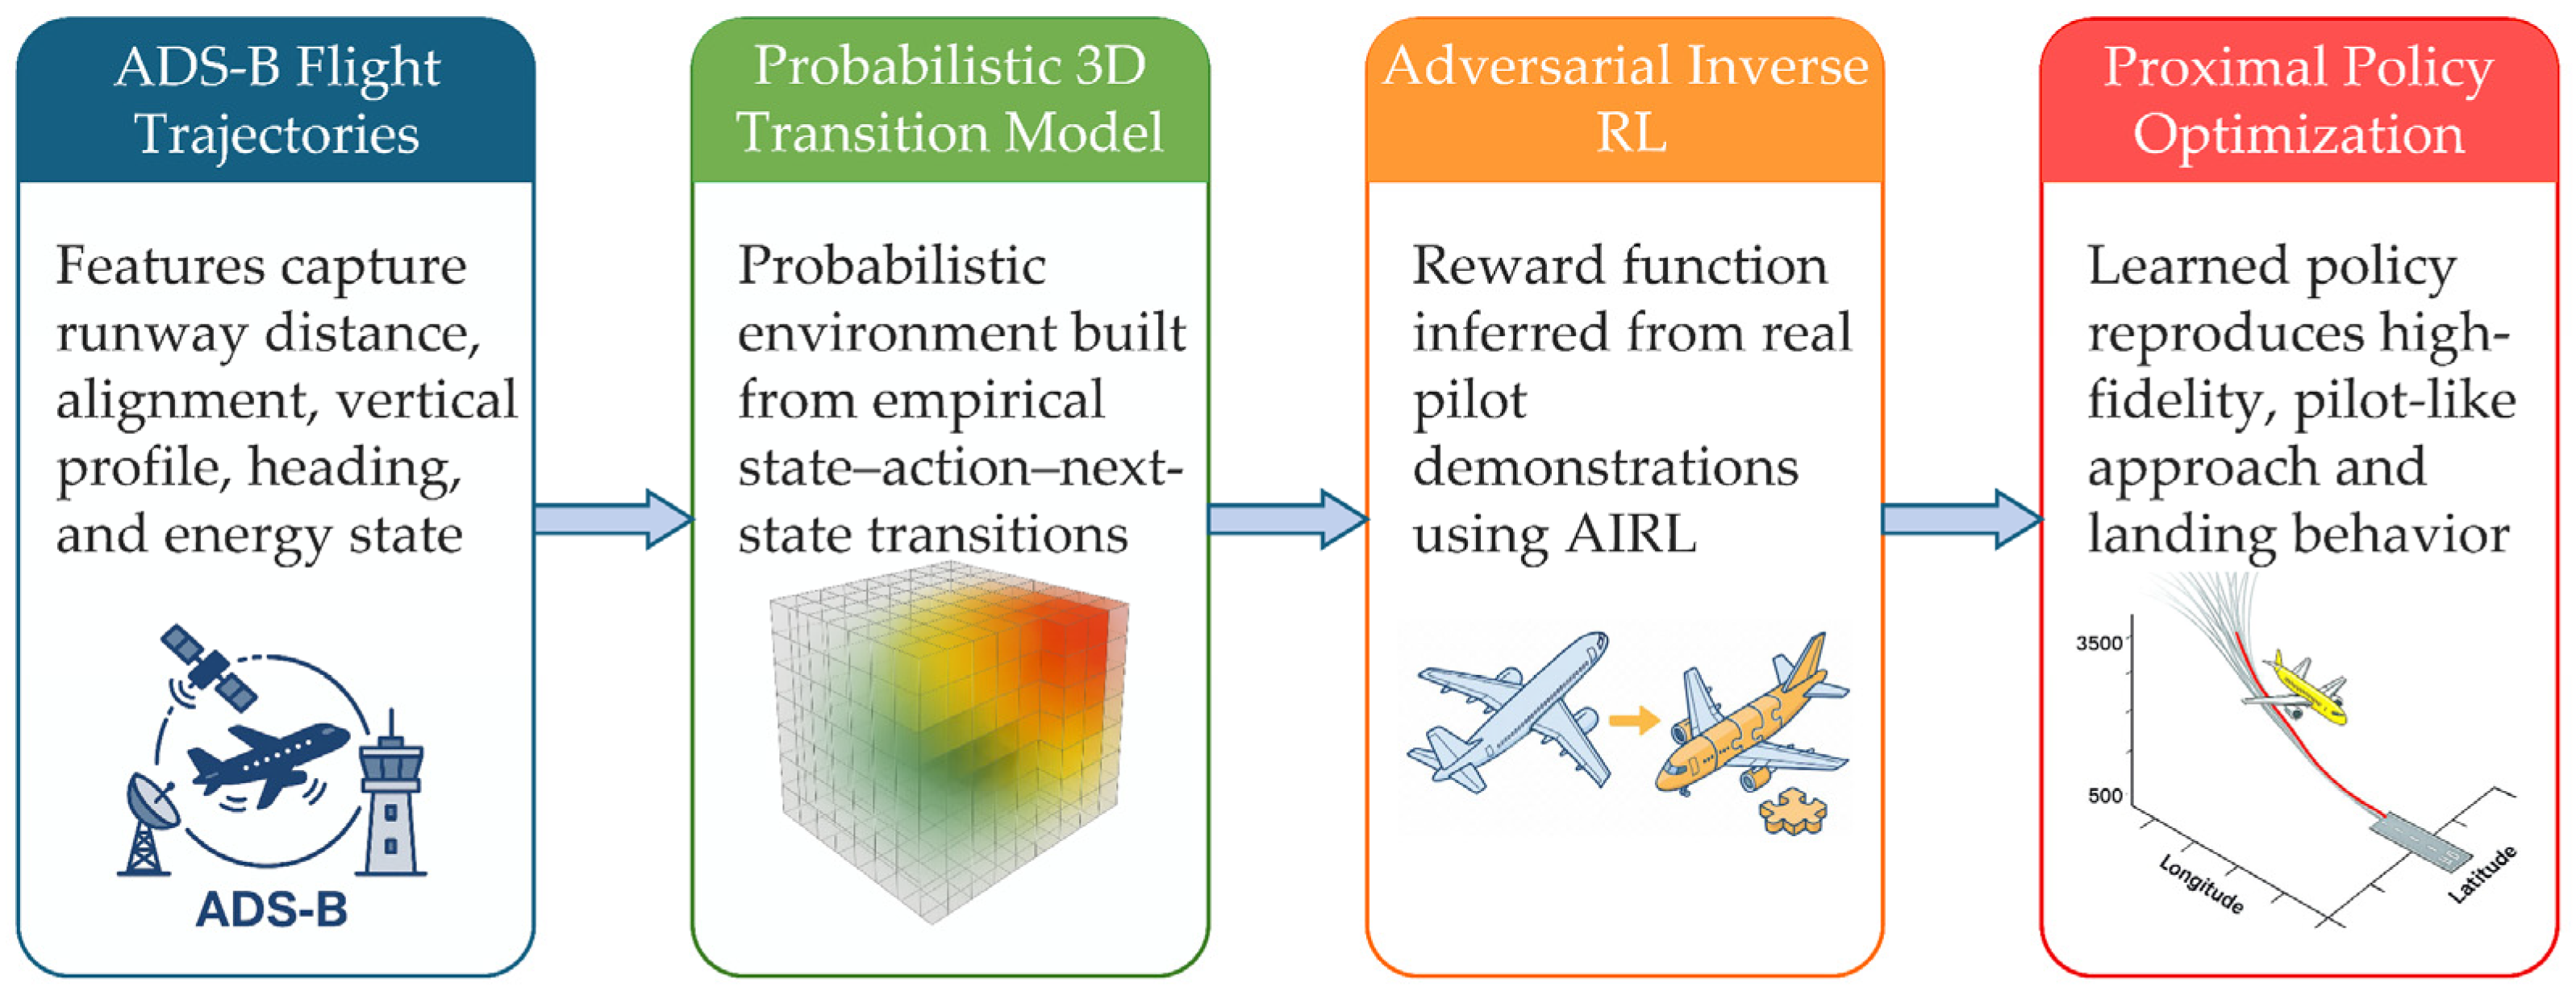
The principal hyperparameters used in both training stages are summarized in Table 3. The entire framework of this project is presented in Figure 4.
Table 3.
Training configuration for AIRL and R-PPO stages.
Figure 4.
PILOT (Policy Inference from Logged Operational Trajectories) framework for Robust Aircraft Approach Guidance.
To promote stable learning, a curriculum mechanism controlled the initial-state distribution and success criteria. Early in training, episodes began close to touchdown (≤5 NM) with a wide heading tolerance ( ≤ 20°). As training progressed, the curriculum gradually extended the start distribution to full-approach distances (up to 15 NM) while tightening the success tolerance to 15° and eventually 10°.
This scheduling was implemented using a linear annealing function, as shown in (9):
where and denote the near-start ratios at the beginning and end of training. This approach allows the policy to master the final approach region before confronting the full approach envelope.
8. Validation and Evaluation
We implement the proposed PILOT framework to learn a landing policy that replicates expert approach behavior. The policy is trained on recorded expert trajectories and evaluated using Monte Carlo rollouts initialized from randomly sampled start states drawn from the dataset. Each rollout is simulated until near touchdown or until a safety-constraint violation occurs. To enable point-wise comparison with expert behavior, all trajectories are re-parameterized by distance to the runway threshold D (ranging from 15 NM to 0 NM), allowing for a direct, point-by-point comparison with expert behavior. We report results from 500 agent rollouts and compare them against 1039 expert approaches. For each variable of interest, we compute the mean profile and the corresponding range across rollouts for both the agent and the expert, assessing agreement in terms of both central tendency and dispersion.
Computations were performed on a standard workstation (Intel Core i7 CPU, 16 GB RAM, single NVIDIA GPU), demonstrating that the PILOT framework can be trained reliably without the need for specialized hardware.
We validate the learned policy against expert trajectories using profile matching over distance and operational speed plausibility at landing. We report these comparisons for:
Figure 5.
Comparison of agent and expert approach profiles versus distance to runway threshold D (NM): (a) altitude (ft); (b) speed (Kt); (c) glide slope (ft/NM); and (d) vertical speed (fpm); (e) latitude (deg); (f) longitude (deg). Solid lines show the mean, and shaded bands indicate the range.
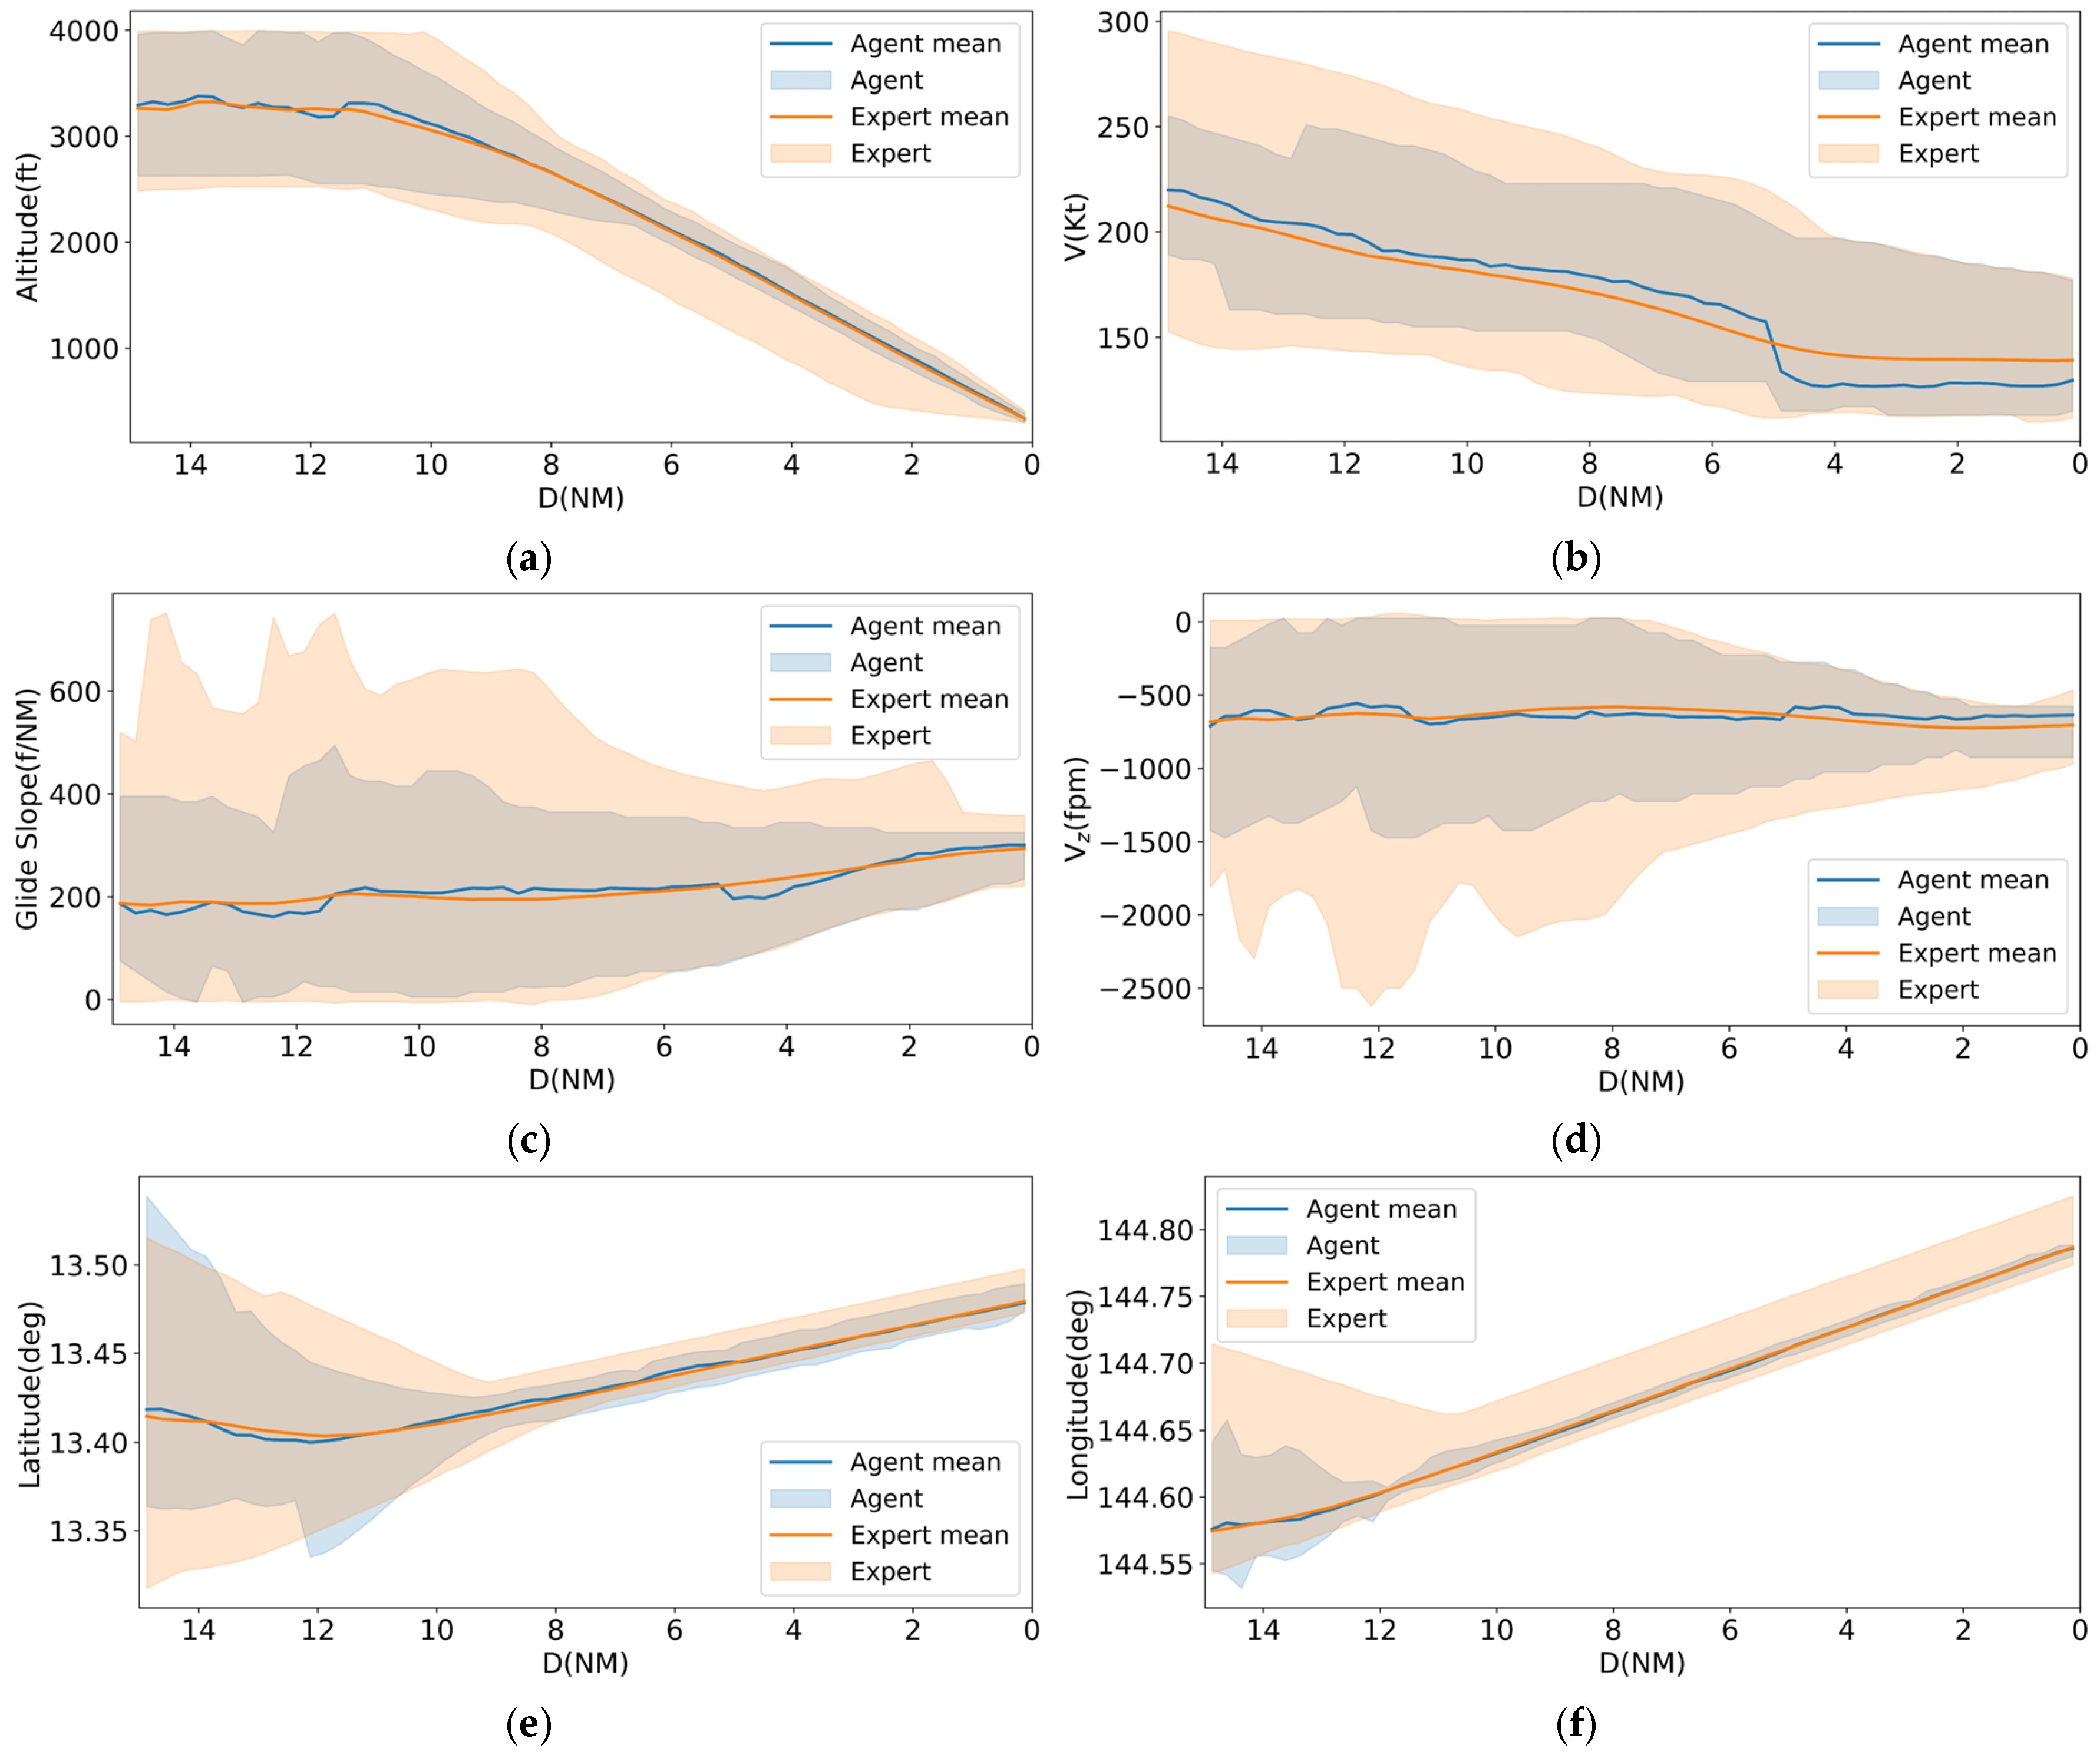
This analysis tests whether the agent matches not only the average behavior but also the dispersion observed in real expert demonstrations. In Figure 5a, the agent’s mean altitude profile closely overlaps the expert’s mean from 15 NM to touchdown, with strong agreement also in the percentile bands. This indicates that the learned policy reliably reproduces the global descent geometry of the approach.
In Figure 5b,c, the agent generally follows the expert trend. Figure 5d shows that both the agent and expert maintain a broadly consistent descent rate on average. However, the agent exhibits larger short-range fluctuations at some distances.
Latitude and longitude comparisons (Figure 5e,f) show strong overlap between agent and expert means, with narrowing dispersion as D→0. This is a positive result, suggesting that the policy is not only reproducing the vertical profile correctly but also aligning laterally.
Table 4 provides a quantitative assessment of the agreement between the agent and expert trajectories over the 0–15 NM approach segment. For each flight variable, we report the mean error, and RMSE across all rollouts. These metrics complement the visual comparisons in Figure 5, confirming that the learned PILOT policy closely reproduces the expert approach, both in terms of average behavior and point-wise deviations along the distance to the runway threshold.
Table 4.
Quantitative comparison of agent vs. expert flight trajectories (0–15 NM to touchdown).
For instance, the RMSE values indicate that altitude deviations remain within ~60 ft on average, while lateral deviations (latitude and longitude) are below 0.005° (~300–500 m), demonstrating high fidelity in both vertical and lateral profiles.
In support of the landing-quality assessment, we verify that the learned policy produces physically plausible approach and touchdown speeds consistent with standard landing envelopes. Table 5 reports representative landing reference speeds (at MLW) and estimated stall speeds for the aircraft types present in the dataset. These values contextualize the touchdown speed distributions observed in both expert trajectories and agent rollouts and provide a sanity check that the learned policy operates within expected landing-speed regimes. Table 5 also highlights that the expert demonstrations span a wider operating range across aircraft types.
Table 5.
Representative landing reference speed (at MLW) and estimated stall speed for aircraft types in the dataset.
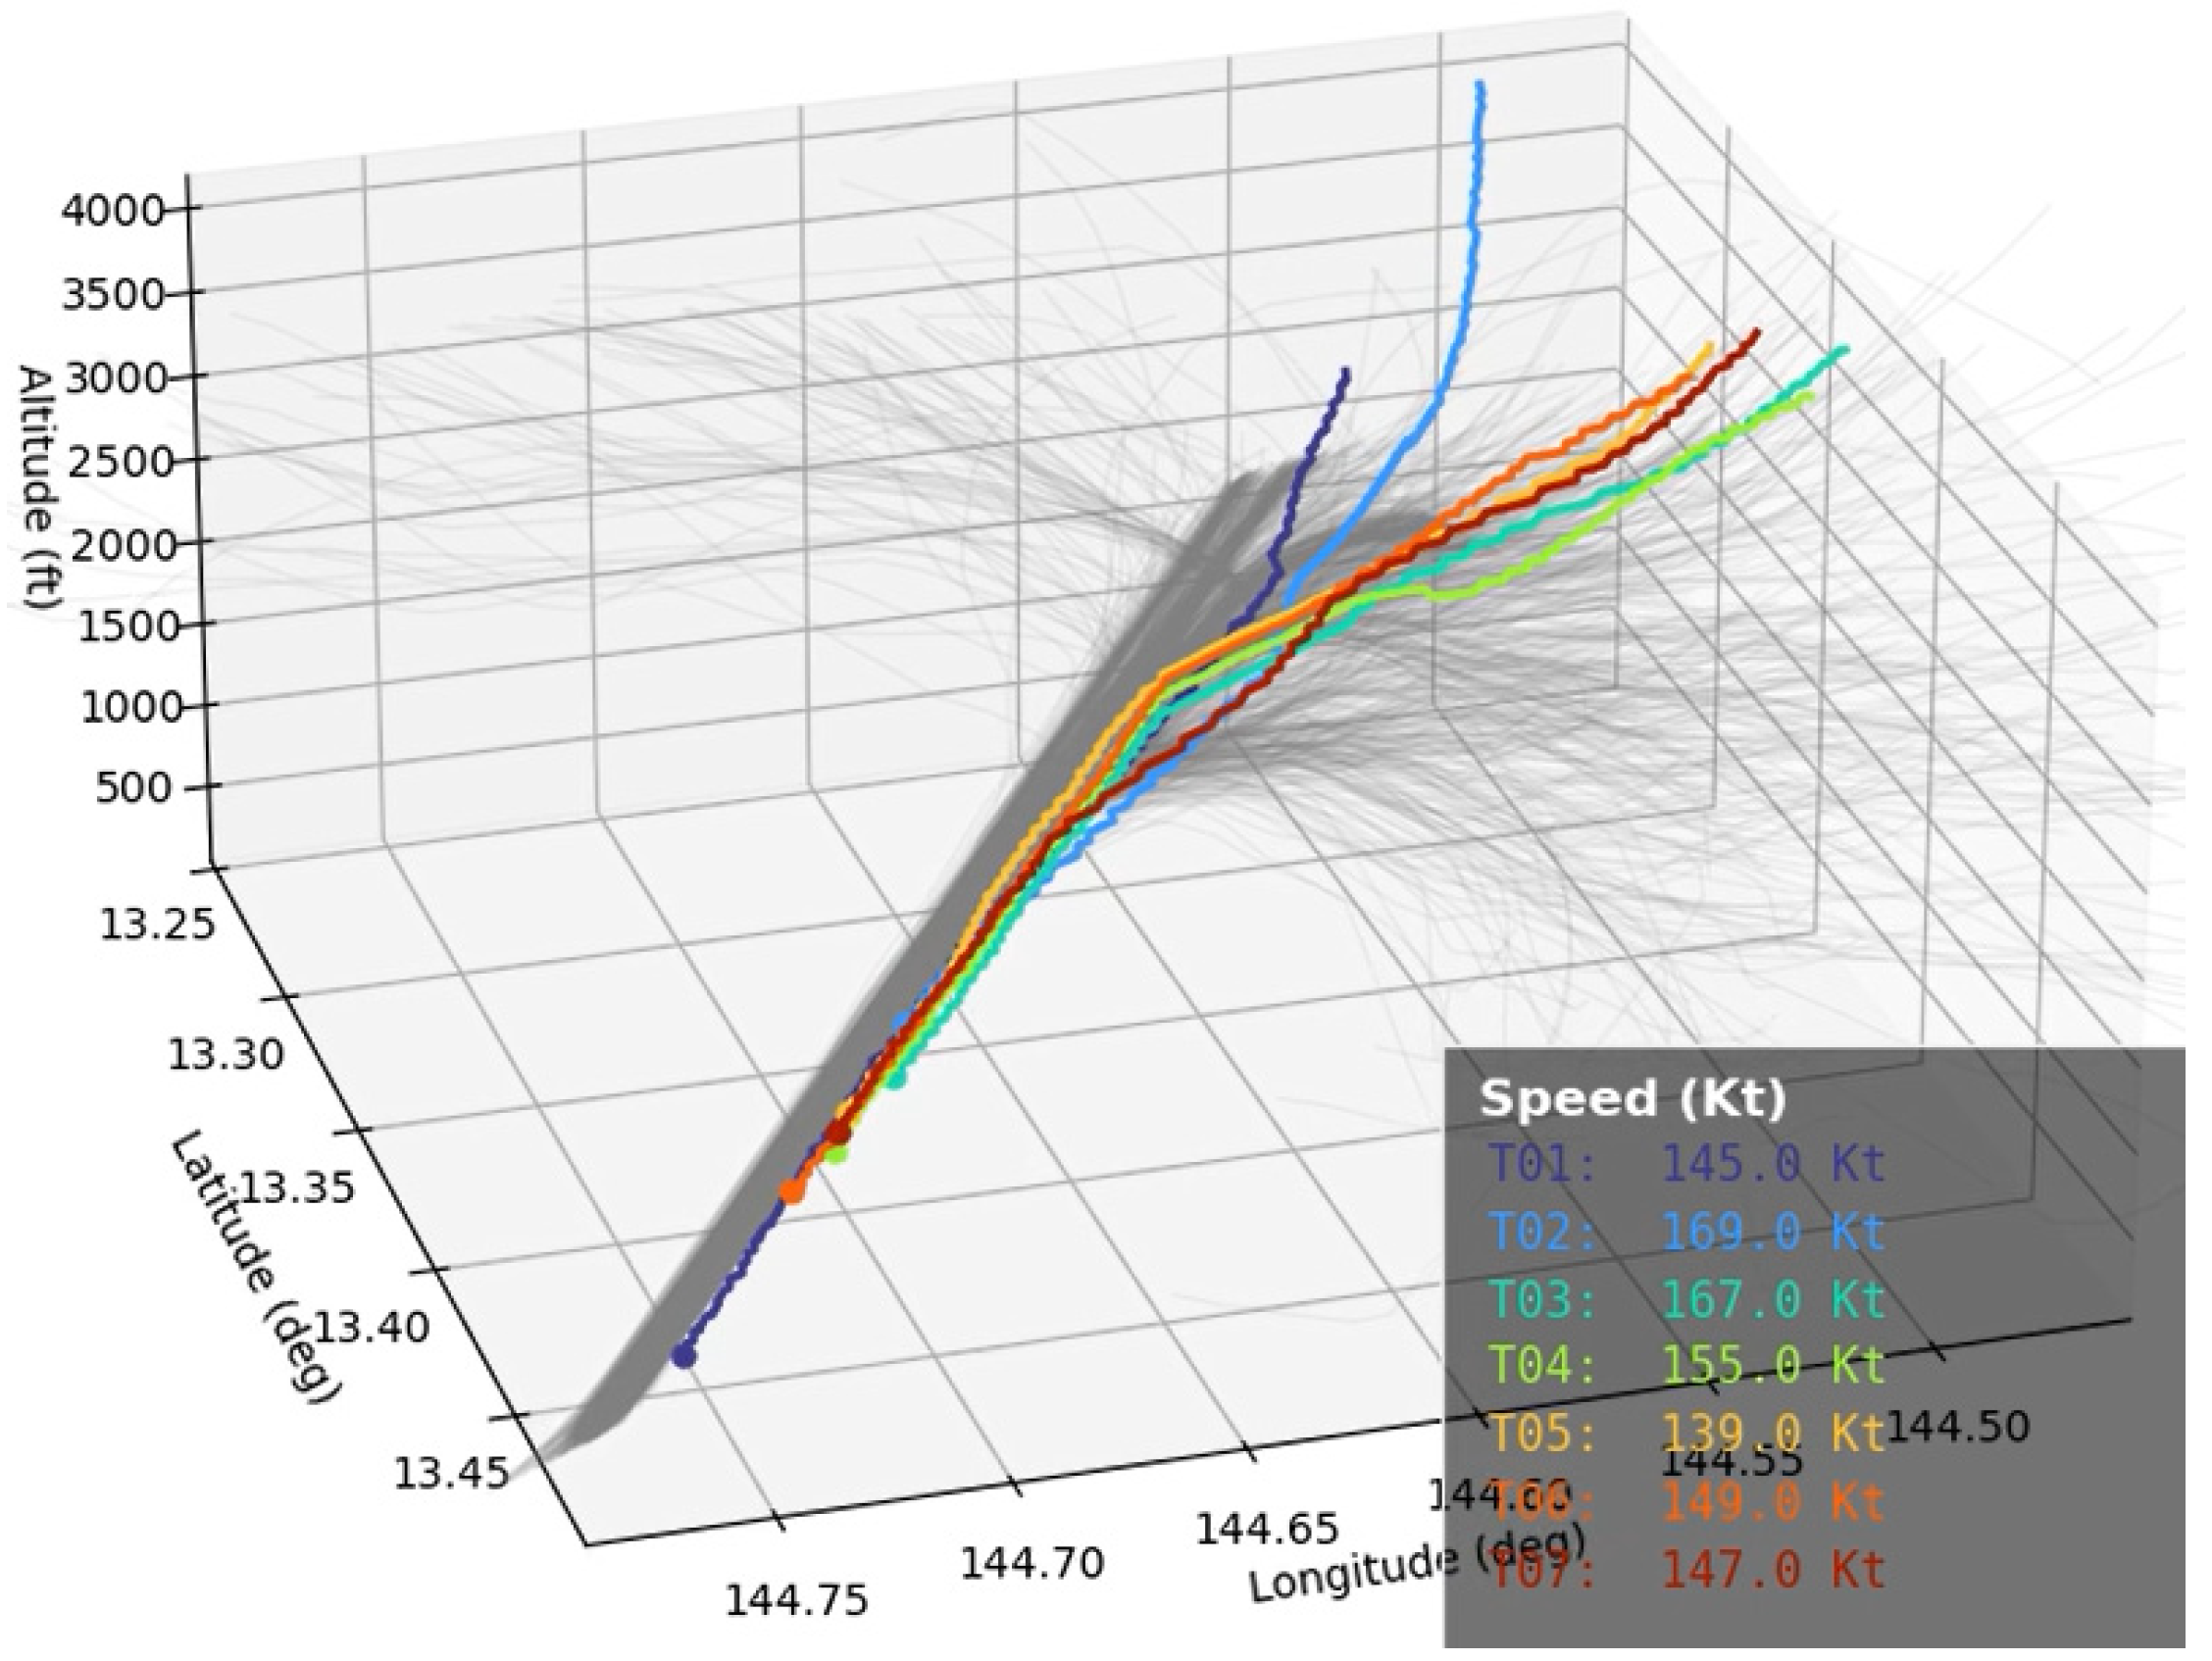
To complement the scalar profile comparisons in Figure 5; we provide Supplementary Video S1 (Figure 6), a synchronized 3D replay of expert and agent approaches. The animation is included as a qualitative diagnostic to (i) reveal transient corrections and short-horizon deviations that may be partially obscured in percentile bands, and (ii) enable visual consistency checks between 3D path geometry and the corresponding scalar profiles (altitude, descent rate, and speed).
Figure 6.
Expert trajectories (gray) overlaid with randomly sampled trajectories generated by the learned policy (from Supplementary Video S1).
Overall, the combined evidence suggests that the learned policy captures key aspects of expert approach behavior while remaining within physically observed operating regimes. At the same time, residual mismatch in variables closely tied to touchdown quality indicates clear opportunities for improvement within the current data regime. Future work will focus on (i) improving representation and feature design for the approach phase (e.g., better normalization, distance-conditioned features, and more informative terminal descriptors) to reduce short-range oscillations and better match descent rate behavior near the runway threshold, and (ii) extending the dataset with higher-fidelity near-ground measurements to explicitly model the flare phase, which is not reliably observable from the current ADS-B-based trajectories.
9. Discussion and Future Works
The PILOT framework successfully learns robust, pilot-consistent landing policies directly from operational ADS-B trajectories. Across 1039 real-world approaches at Guam International Airport (PGUM), the learned policy closely reproduces vertical, lateral, and energy profiles of expert pilots, maintaining physically plausible terminal conditions. Mean profiles and variability ranges of key variables (including altitude, airspeed, glide slope, vertical speed, and lateral alignment) align closely with expert demonstrations, demonstrating that data-driven methods can capture implicit pilot decision-making without analytic flight dynamics models or hand-crafted reward functions.
Although this study focuses on PGUM, the PILOT framework is not inherently tied to a specific airport geometry. Its state-based representation supports conceptual transferability across airports with different terrain elevations or runway orientations. Nonetheless, the learned reward function reflects procedural and environmental characteristics embedded in the expert data. Deployment at a new airport would therefore require fine-tuning or re-learning from local trajectories to capture site-specific constraints such as terrain-limited descent profiles, crosswind distributions, or procedural approach structures. Distinguishing framework generality from instance-specific training is essential for interpreting applicability.
Commercial airport operational environments can be conceptually characterized along three axes: density-driven performance degradation (temperature, pressure, humidity), wind field complexity (including crosswind components), and terrain-induced constraints. The present study samples the hot–humid, low-elevation regime, while high-altitude or strong crosswind environments remain targets for future extension.
Certain limitations should be acknowledged and can be categorized into data-related, modeling, and operational aspects.
Data limitations: The framework relies exclusively on 1 Hz kinematic ADS-B trajectory data, which capture position, velocity, and heading but omit aircraft configuration states, thrust settings, mass variations, control-surface inputs, and high-fidelity near-ground dynamics. As a result, the learned policy reflects trajectory-level behavioral patterns rather than actuator-level control mechanisms. Complementary higher-rate surveillance or onboard flight data would enhance state fidelity and enable more detailed modeling of flare and touchdown phases, which are underrepresented in ADS-B data.
Modeling assumptions: The proposed framework adopts discretized state and action representations, Markovian transition assumptions, and reward recovery through AIRL under finite trajectory samples. While these choices enable stable and interpretable training, they may constrain policy expressiveness compared to continuous.
Operational constraints: The learned policies are validated offline against historical trajectories and Monte Carlo rollouts. Real-world deployment would require additional verification, safety envelopes, redundancy strategies, and certification procedures before integration into operational flight control systems.
Future work will focus on enriching state representation, improving feature engineering (e.g., distance-conditioned features and enhanced normalization), and expanding the dataset to include higher-fidelity near-ground measurements.
Finally, the framework enables data-driven, adaptive approach paths that respect safety limits and pilot-consistent behavior. Probabilistic, airport-specific minima derived from operational evidence could gradually supplement traditional rule-based minima, reducing unnecessary go-arounds, lowering pilot workload, and improving consistency, especially at complex or meteorologically challenging airports. Extending this approach across multiple airports and aircraft types, combined with formal safety verification, offers a scientifically grounded path toward more automated, adaptive, and safer landing operations.
Supplementary Materials
The following supporting information can be downloaded at: https://www.mdpi.com/article/10.3390/make8030071/s1.
Author Contributions
Conceptualization, S.M.-B.M. and E.A.; methodology, E.A.; software, E.A.; validation, E.A. and S.M.-B.M.; formal analysis, E.A.; investigation, S.M.-B.M. and E.A.; data curation, E.A.; writing—original draft preparation, E.A. and S.M.-B.M.; writing—review and editing, S.M.-B.M.; visualization, E.A.; supervision, S.M.-B.M. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Data Availability Statement
The data presented in this study are available upon reasonable request from the corresponding author.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Armstrong, M. Infographic: Most Airplane Accidents Happen During Landing. Statista Daily Data. Available online: https://www.statista.com/chart/31529/most-airplane-accidents-happen-during-landing (accessed on 25 February 2026).
- Fu, J.; Luo, K.; Levine, S. Learning robust rewards with adversarial inverse reinforcement learning. In Proceedings of the 6th International Conference on Learning Representations (ICLR), Vancouver, BC, Canada, 30 April–3 May 2018. [Google Scholar]
- Sun, J.; Yu, L.; Dong, P.; Lu, B.; Zhou, B. Adversarial inverse reinforcement learning with self-attention dynamics model. IEEE Robot. Autom. Lett. 2021, 6, 1880–1886. [Google Scholar] [CrossRef] [Scilit]
- Venuto, D.; Chakravorty, J.; Boussioux, L.; Wang, J.; McCracken, G.; Precup, D. OIRL: Robust adversarial inverse reinforcement learning with temporally extended actions. arXiv 2020, arXiv:2002.09043. [Google Scholar] [CrossRef] [Scilit]
- Arnob, S.Y. Off-policy adversarial inverse reinforcement learning. arXiv 2020, arXiv:2005.01138. [Google Scholar] [CrossRef] [Scilit]
- Zhan, M.; Fan, J.; Guo, J. Generative adversarial inverse reinforcement learning with deep deterministic policy gradient. IEEE Access 2023, 11, 87732–87746. [Google Scholar] [CrossRef] [Scilit]
- Yuan, M.; Pun, M.-O.; Chen, Y.; Cao, Q. Hybrid adversarial inverse reinforcement learning. arXiv 2021, arXiv:2102.02454. [Google Scholar]
- Wang, P.; Liu, D.; Chen, J.; Chan, C.-Y. Adversarial inverse reinforcement learning for decision making in autonomous driving. arXiv 2019, arXiv:1911.08044v1. [Google Scholar]
- Wang, P.; Liu, D.; Chen, J.; Li, H.; Chan, C.-Y. Decision making for autonomous driving via augmented adversarial inverse reinforcement learning. arXiv 2019, arXiv:1911.08044. [Google Scholar]
- Yu, L.; Song, J.; Ermon, S. Multi-agent adversarial inverse reinforcement learning. arXiv 2019, arXiv:1907.13220. [Google Scholar] [CrossRef] [Scilit]
- Pattanayak, K.; Krishnamurthy, V.; Berry, C. Inverse-inverse reinforcement learning: How to hide strategy from an adversarial inverse reinforcement learner. In Proceedings of the IEEE Conference on Decision and Control (CDC), Cancun, Mexico, 6–9 December 2022. [Google Scholar]
- Chen, J.; Lan, T.; Aggarwal, V. Hierarchical adversarial inverse reinforcement learning. IEEE Trans. Neural Netw. Learn. Syst. 2023, 35, 17549–17558. [Google Scholar] [CrossRef] [Scilit]
- Xiang, G.; Li, S.; Shuang, F.; Gao, F.; Yuan, X. SC-AIRL: Share-critic in adversarial inverse reinforcement learning for long-horizon tasks. IEEE Robot. Autom. Lett. 2024, 9, 3179–3186. [Google Scholar] [CrossRef] [Scilit]
- Zhu, L.; Wang, J.; Wang, Y.; Ji, Y.; Ren, J. DRL-RNP: Deep Reinforcement Learning-Based Optimized RNP Flight Procedure Execution. Sensors 2022, 22, 6475. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Sun, H.; Zhang, W.; Yu, R.; Zhang, Y. Motion planning for mobile robots—Focusing on deep reinforcement learning: A systematic review. IEEE Access 2021, 9, 69061–69081. [Google Scholar] [CrossRef] [Scilit]
- Richter, D.J.; Calix, R.A. QPlane: An Open-Source Reinforcement Learning Toolkit for Autonomous Fixed Wing Aircraft Simulation. In Proceedings of the 12th ACM Multimedia Systems Conference, in MMSys ’21; Association for Computing Machinery: New York, NY, USA, 2021; pp. 261–266. [Google Scholar] [CrossRef] [Scilit]
- Wang, W.; Ma, J. A review: Applications of machine learning and deep learning in aerospace engineering and aero-engine engineering. Adv. Eng. Innov. 2024, 6, 54–72. [Google Scholar] [CrossRef] [Scilit]
- Hu, Z.; Wan, K.; Gao, X.; Zhai, Y.; Wang, Q. Deep Reinforcement Learning Approach with Multiple Experience Pools for UAV’s Autonomous Motion Planning in Complex Unknown Environments. Sensors 2020, 20, 1890. [Google Scholar] [CrossRef] [Scilit]
- Pinto Neto, E.C.; Baum, D.M.; Almeida, J.R.d., Jr.; Camargo, J.B., Jr.; Cugnasca, P.S. Deep Learning in Air Traffic Management (ATM): A Survey on Applications, Opportunities, and Open Challenges. Aerospace 2023, 10, 358. [Google Scholar] [CrossRef] [Scilit]
- Hu, J.; Yang, X.; Wang, W.; Wei, P.; Ying, L.; Liu, Y. Obstacle Avoidance for UAS in Continuous Action Space Using Deep Reinforcement Learning. IEEE Access 2022, 10, 90623–90634. [Google Scholar] [CrossRef] [Scilit]
- Ali, H.; Pham, D.-T.; Alam, S.; Schultz, M. A Deep Reinforcement Learning Approach for Airport Departure Metering Under Spatial–Temporal Airside Interactions. IEEE Trans. Intell. Transp. Syst. 2022, 23, 23933–23950. [Google Scholar] [CrossRef] [Scilit]
- Choi, J.; Kim, H.M.; Hwang, H.J.; Kim, Y.-D.; Kim, C.O. Modular Reinforcement Learning for Autonomous UAV Flight Control. Drones 2023, 7, 418. [Google Scholar] [CrossRef] [Scilit]
- Chronis, C.; Anagnostopoulos, G.; Politi, E.; Dimitrakopoulos, G.; Varlamis, I. Dynamic Navigation in Unconstrained Environments Using Reinforcement Learning Algorithms. IEEE Access 2023, 11, 117984–118001. [Google Scholar] [CrossRef] [Scilit]
- Wada, D.; Araujo-Estrada, S.A.; Windsor, S.; Wada, D.; Araujo-Estrada, S.A.; Windsor, S. Unmanned Aerial Vehicle Pitch Control under Delay Using Deep Reinforcement Learning with Continuous Action in Wind Tunnel Test. Aerospace 2021, 8, 258. [Google Scholar] [CrossRef] [Scilit]
- Azar, A.T.; Koubaa, A.; Ali Mohamed, N.; Ibrahim, H.A.; Ibrahim, Z.F.; Kazim, M.; Ammar, A.; Benjdira, B.; Khamis, A.M.; Hameed, I.A.; et al. Drone deep reinforcement learning: A review. Electronics 2021, 10, 999. [Google Scholar] [CrossRef] [Scilit]
- Lou, J.; Yuksek, B.; Inalhan, G.; Tsourdos, A. Real-Time On-the-Fly Motion Planning for Urban Air Mobility via Updating Tree Data of Sampling-Based Algorithms Using Neural Network Inference. Aerospace 2024, 11, 99. [Google Scholar] [CrossRef] [Scilit]
- Zhu, H.; Chen, M.; Han, Z.; Lungu, M. Inverse Reinforcement Learning-Based Fire-Control Command Calculation of an Unmanned Autonomous Helicopter Using Swarm Intelligence Demonstration. Aerospace 2023, 10, 309. [Google Scholar] [CrossRef] [Scilit]
- Brunke, L.; Greeff, M.; Hall, A.W.; Yuan, Z.; Zhou, S.; Panerati, J.; Schoellig, A.P. Safe learning in robotics: From learning-based control to safe reinforcement learning. Annu. Rev. Control. Robot. Auton. Syst. 2022, 5, 411–444. [Google Scholar] [CrossRef] [Scilit]
- WMO Codes Registry: wmdr/DataFormat/FM-15-metar. Available online: https://codes.wmo.int/wmdr/DataFormat/FM-15-metar (accessed on 5 January 2026).
- Iowa Environmental Mesonet. Available online: https://mesonet.agron.iastate.edu/request/download.phtml (accessed on 5 January 2026).
- Climate Trends and Projections for Guam|U.S. Geological Survey. Available online: https://www.usgs.gov/publications/climate-trends-and-projections-guam (accessed on 5 January 2026).
- O’Donnell, M. Airport Design, Updates to the standards for Taxiway Fillet Design, Advisory Circular No.:150-5300-13A; FAA: Washington, DC, USA, 2014.
- Freedman, D.; Diaconis, P. On the histogram as a density estimator: L2 theory. Z. Wahrscheinlichkeitstheorie Verwandte Geb. 1981, 57, 453–476. [Google Scholar] [CrossRef] [Scilit]
- Ng, A.Y.; Harada, D.; Russell, S. Policy Invariance under Reward Transformations: Theory and Application to Reward Shaping. In Proceedings of the 16th International Conference on Machine Learning (ICML), Bled, Slovenia, 27–30 June 1999; Morgan Kaufmann: San Francisco, CA, USA, 1999; pp. 278–287. [Google Scholar]
- Schulman, J.; Wolski, F.; Dhariwal, P.; Radford, A.; Klimov, O. Proximal Policy Optimization Algorithms. arXiv 2017, arXiv:1707.06347. [Google Scholar] [CrossRef] [Scilit]
- Aircraft Characteristics Database|Federal Aviation Administration. Available online: https://www.faa.gov/airports/engineering/aircraft_char_database (accessed on 31 December 2025).
- Flight Standards. Use of Aircraft Approach Category During Instrument Approach Operations; FAA: Washington, DC, USA, 2023.

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.