


Abstract
This study proposes a hybrid artificial intelligence (AI) framework for graduate subject allocation that enhances fairness, transparency, and operational efficiency in higher education institutions. Traditional subject allocation processes are predominantly manual and time-consuming in increasingly complex academic environments. The proposed framework integrates a custom Python-based rule engine for institutional constraint reasoning with advanced deep learning models, including XGBoost, Wide-and-Deep Neural Networks (WDNNs), and Graph Neural Networks (GNNs), to ensure policy-compliant and data-driven subject allocation decisions. Subsequently, a systematic hyperparameter optimization strategy is applied to enhance predictive accuracy and model stability across all architectures. Experimental evaluation demonstrates that the proposed framework significantly improves predictive and ranking performance. The GNNs model achieved the highest results with Accuracy = 0.964, Precision = 0.953, Recall = 0.941, F1-score = 0.947, and AUC = 0.976, outperforming WDNN (Accuracy = 0.956, AUC = 0.972) and XGBoost (Accuracy = 0.934, AUC = 0.942). Ranking effectiveness was also validated with HR@10 = 0.784 and NDCG@10 = 0.622. Feature-importance analysis using SHAP revealed that Digital Pedagogical Competence (12.6%), Research Productivity (10.8%), and Postgraduate Supervision (9.7%) are the most influential factors in allocation decisions. To ensure institutional alignment, a multi-objective reranking mechanism was introduced to balance suitability, workload fairness, research alignment, and diversity. This approach reduced workload variance from 0.26 to 0.18 and improved research–subject alignment by 21%. Overall, the proposed framework provides a scalable, explainable, and data-driven solution for optimizing graduate subject allocation in modern higher education systems.
1. Introduction
In recent years, higher education institutions have faced increasing complexity in curriculum design and subject allocation due to the rapid expansion of course offerings, the growth of interdisciplinary programs, and the diversity of student profiles [1]. At the same time, the advent of large-scale educational data (student records, faculty profiles, course metadata) creates opportunities to apply intelligent systems for decision support [2]. Recommendation systems (RSs) have emerged as crucial tools for filtering choices, suggesting alternatives, and guiding decision-making in high-dimensional, constrained domains [3]. In the educational domain, RSs have traditionally supported students [4]. However, relatively few studies consider RSs in faculty workload and subject allocation, which involve multiple stakeholders (students, faculty, programs) and hard constraints (prerequisites, scheduling, capacity). The need to allocate subjects optimally is especially pronounced in graduate studies, where curriculum progress, research alignment, and faculty specialization are of great importance [5]. Traditionally, subject allocation has been rule-based (program policies, prerequisites, faculty load), overseen by academic advisers and administrators. However, such manual systems have limitations: they may not account for latent factors such as faculty research alignment, student interest vectors, or the interplay among faculty–student–subject relationships [6]. Meanwhile, advances in machine learning (ML) and deep learning (DL) offer greater capacity to model complex, relational, and higher-order structures [7]. Knowledge-graph-enhanced recommendation systems extend beyond traditional collaborative filtering and content-based methods by leveraging side information and relational embeddings, thus improving performance and explainability [8]. For example, GNNs applied to heterogeneous educational graphs (students, courses, faculty) have demonstrated superior ranking accuracy for course recommendations [9]. In the context of subject allocation, these methods can encode faculty expertise, research output, student interests, program relationships, and scheduling constraints into one unified graph of entities and relations. Although educational recommender systems have achieved significant success in course recommendation, adaptive learning, and personalized education, most existing studies focus primarily on student-centered recommendation tasks and rarely address faculty-centric subject allocation problems [10]. Furthermore, previous approaches typically emphasize prediction accuracy while overlooking institutional policies, workload fairness, research alignment, and explainability requirements that are critical in graduate-level academic management. Existing workload allocation frameworks often rely on rule-based or optimization techniques that lack adaptive learning capabilities and cannot effectively model complex relationships among faculty members, subjects, and academic programs.
To address these limitations, the present study proposes a novel knowledge-based recommendation framework that integrates a custom institutional rule engine, heterogeneous knowledge graph representation, Graph Neural Networks (GNNs), explainable artificial intelligence (XAI), and multi-objective optimization. Unlike previous studies, the proposed framework simultaneously considers faculty expertise, institutional eligibility constraints, workload balance, postgraduate supervision capacity, research specialization, and academic policy compliance within a unified recommendation architecture. This combination enables transparent, explainable, and policy-compliant subject allocation decisions while maintaining high predictive performance and institutional applicability. To improve readability and methodological transparency, the manuscript adopts consistent terminology and standardized notation throughout all sections. Redundant descriptions have been consolidated where appropriate, and methodological explanations are presented only once within the relevant subsection to avoid repetition while maintaining sufficient technical detail for reproducibility.
In the remainder of this paper, we present a literature review on educational recommendation systems, knowledge graph-based recommendations, and faculty workload allocation frameworks (Section 2), describe the research methodology (Section 3), present evaluation performances (Section 4), discuss experiment results for practice (Section 5), and conclude with conclusions and future work (Section 6 and Section 7).
2. Literature Review
Educational recommender systems have evolved from traditional collaborative filtering and content-based approaches toward knowledge-aware and graph-based learning frameworks [11]. Recent advances in knowledge graphs and GNNs have enabled recommendation systems to capture complex semantic and relational dependencies among educational entities, thereby improving recommendation accuracy, contextual relevance, and interpretability [12]. Despite these advances, existing studies primarily focus on student-centered recommendation tasks and rarely address institutional decision-support problems involving faculty assignment, workload balancing, policy compliance, and academic resource allocation. Consequently, there remains a need for intelligent recommendation frameworks that integrate relational learning, institutional knowledge, and explainable decision-making in higher education environments. By incorporating semantic relationships among courses, academic domains, and learner profiles, knowledge graph–based recommenders can generate more accurate and personalized recommendations, particularly when user information is limited. Such approaches improve recommendation quality by leveraging contextual knowledge and hidden associations between educational entities, thereby supporting more informed academic decision-making and curriculum planning [13]. Recent advancements in GNN-based recommender systems have demonstrated significant improvements in modeling complex relationships among users, items, and contextual factors. GNNs approach effectively capture graph-structured interactions and deliver improved recommendation performance while addressing key challenges such as fairness, diversity, explainability, and transparency. These characteristics make GNN-based frameworks particularly suitable for educational decision-support applications, where recommendation outcomes must be both accurate and interpretable [14]. By integrating structured domain knowledge with recommendation algorithms, these approaches improve the relevance of recommendations, contextual understanding, and decision quality. Such knowledge-driven frameworks provide a robust foundation for educational recommendation systems, particularly in scenarios that require intelligent matching of academic resources, expertise, and institutional objectives [15]. Recent advancements in deep learning architectures (Neural Collaborative Filtering (NCF), WDNNs, and GNNs have significantly expanded the capacity of recommendation systems to learn latent representations and multi-relational patterns that traditional statistical models often fail to capture [16]. These models transcend simple input–output prediction by embedding semantic and structural relationships among diverse entities such as students, faculty, subjects, and institutional rules. In educational applications, such models enable reasoning over both explicit relationships (e.g., teaching history, research specialization) and implicit associations (e.g., mentoring effectiveness, digital teaching affinity). Knowledge Graphs (KGs) have further augmented this capability by structuring educational data into interconnected ontologies that allow semantic reasoning. Studies have shown that KG-based educational recommenders enhance adaptive learning pathways, dynamic course sequencing, and skill mapping—resulting in improved personalization and cognitive alignment between learners and content [17]. However, despite these successes, the application of KGs and deep learning to academic management remains underexplored. Most prior work focuses on student-side personalization, leaving institutional decision-making largely rule-driven and manually optimized. Recent hybrid frameworks that integrate knowledge-based reasoning with deep representation learning represent a transformative paradigm shift, combining the transparency of expert systems with the adaptability of neural models [18]. Hybrid AI models enhance graduate subject allocation by combining institutional rules with data-driven learning to improve fairness and predictive accuracy. In particular, GNNs effectively models relationships among faculty, subjects, and programs, enabling more accurate and interpretable recommendations [19]. Additionally, integrating reinforcement learning (RL) allows systems to adapt dynamically to policy changes and feedback. Recent studies emphasize that fairness and explainability are essential in educational AI, ensuring ethical, transparent, and compliant decision-making [20]. In the context of faculty workload allocation, scholars have identified significant challenges in balancing quantitative factors (e.g., teaching experience, academic rank, and administrative duties) with qualitative indicators (e.g., mentoring quality, research supervision, and digital pedagogical skills) [8]. Current decision models often fail to integrate these diverse dimensions holistically, leading to inconsistent workload distribution and potential faculty dissatisfaction. Few frameworks treat the triadic relationship among faculty, subjects, and programs as a co-dependent decision space in which optimizing one dimension directly influences the others. Knowledge graph-enhanced hybrid recommender systems directly address this gap by enabling multi-objective optimization while preserving interpretable rule traces for administrative validation [21]. Empirical studies have demonstrated that combining domain ontologies and explicit workload constraints with neural learning architectures substantially improves both accuracy and transparency, making such systems well-suited for institutional deployment. The existing literature provides compelling evidence of the potential of deep learning-based, knowledge graph-augmented recommender systems to address complex educational challenges. However, significant gaps remain regarding faculty-centric subject allocation, hybrid knowledge-driven optimization, and real-world validation within university environments. The comparison between existing educational recommendation frameworks and the proposed approach is given in Table 1.
Table 1.
Comparison between existing educational recommendation frameworks and the proposed approach.
To ensure compliance with institutional policies, the proposed framework incorporates a custom Python-based rule engine that operates as a pre-processing and constraint-filtering layer. The rule engine encodes explicit academic regulations, including qualification requirements, workload limits, supervision eligibility, and subject-specific teaching policies, using deterministic conditional logic statements. These rules generate an eligibility mask that filters infeasible faculty–subject assignments before graph construction. Consequently, only policy-compliant relationships are represented within the knowledge graph and subsequently processed by the GNNs model. This hybrid design combines the transparency of rule-based reasoning with the adaptive learning capability of deep neural networks, thereby improving both recommendation validity and institutional alignment. The overarching goal of this research is to design and validate a knowledge-based deep learning framework that intelligently automates and optimizes subject allocation in graduate programs, ensuring fairness, transparency, and institutional alignment. Building on advances in GNNs and knowledge-based reasoning, the study seeks to transform the traditional rule-driven subject-assignment process into a data-driven, interpretable, and adaptive decision-support system.
To achieve this overarching goal, the study is guided by the following specific objectives:
- To design a hybrid knowledge-based GNNs framework that integrates explicit institutional rules (e.g., qualification requirements, workload limits, supervision policies) with data-driven learning from historical allocation patterns.
- To construct a comprehensive indicator–subject knowledge graph that captures semantic and relational dependencies among faculty members, subjects, research domains, and workload profiles, enabling contextual reasoning within the allocation process.
- To develop a GNN-based allocation model that learns attention coefficients representing the importance of faculty indicators in predicting allocation suitability.
- To apply multi-objective optimization techniques that balance allocation goals within a unified allocation function.
- To evaluate the performance and interpretability of the proposed GNNs model against benchmark algorithms (XGBoost, Wide-and-Deep Neural Network, and GNNs) using key metrics such as Accuracy, F1-score, AUC, HR@10, and NDCG@10.
- To design and implement an Indicator Subject Allocation Dashboard (ISAD) that translates model outputs into a usable decision-support interface, allowing administrators to visualize, validate, and adjust allocation outcomes in real time.
- To validate the framework empirically using data from 463 respondents across six faculties at Mahasarakham University, assessing the system’s predictive accuracy, explainability, and institutional applicability.
3. Research Methodology
This study adopts a quantitative approach integrating knowledge-based reasoning, deep learning, and institutional data analysis to develop and evaluate a hybrid intelligent system for subject allocation in graduate studies. The overall research procedure comprises five sequential phases: Section 3.1: ethical approval and data collection process; Section 3.2: problem identification and data preparation; Section 3.3: label construction; Section 3.4: deep learning model development; (D) training objective and regularization; and Section 3.5: validation and interpretation for institutional application.
3.1. Ethical Approval and Data Collection Process
The study was conducted in accordance with the Declaration of Helsinki and approved by the Ethics Committee for Human Research of Mahasarakham University, Thailand (Approval No. 881-843/2025) on 22 December 2025. All participants were informed about the study’s purpose and procedures, and electronic consent was obtained prior to completing the questionnaire. Participants indicated their consent by clicking the agreement statement before proceeding to the survey. All items in the questionnaire were rated on a five-point Likert scale (1 = strongly disagree to 5 = strongly agree). The data collection period extended from 22 December 2025 to 21 January 2026 to ensure clarity, reliability, and contextual relevance of the questions. Based on pilot feedback and expert review, we aim to enhance content validity and ensure comprehensive coverage of academic activities across both science and social science disciplines in the Thai context. The final version of the questionnaire was then approved for data collection.
Data were collected through both online and paper-based questionnaires administered at Mahasarakham University (MSU), Thailand, across six faculties: Science, Engineering, Information Technology, Humanities and Social Sciences, Mahasarakham Business School, and Education. A total of 480 academic staff members participated in the study. Stratified random sampling was employed to achieve proportional representation across faculties and academic ranks, enhancing the representativeness of the sample and minimizing sampling bias. All participants were informed about the study’s purpose and procedures, and electronic consent was obtained prior to completing the questionnaire. For the online survey, electronic consent was secured via a mandatory confirmation checkbox before access to the questionnaire was granted. For the paper-based survey, participants signed a written consent form attached to the questionnaire. Consent documentation, including electronic records and signed forms, was securely stored in a password-protected database accessible only to the research team and retained solely for academic and ethical compliance purposes. Written informed consent was chosen to ensure transparency, accurate documentation, auditability, and strict adherence to institutional ethical standards governing human-subjects research in higher-education contexts. The final dataset comprised 480 eligible academic staff members across six faculties: Science, Engineering, Information Technology, Humanities and Social Sciences, Mahasarakham Business School, and Education. These respondents were associated with approximately 320 graduate-level subjects and a total of 3200 faculty–subject assignment instances after preprocessing and class-balancing procedures. Faculty representation was maintained proportionally through stratified random sampling by academic rank and faculty affiliation to reduce sampling bias. The dataset includes respondents with diverse academic backgrounds, teaching experience, research productivity levels, and administrative responsibilities, thereby providing a comprehensive representation of the institutional academic workforce. Each respondent completed a structured questionnaire containing three parts: (1) demographic information (gender, age, academic rank, years of experience, department), (2) twenty (20) measurable variables related to factors influencing subject allocation, and (3) institutional engagement outcomes such as research contribution and teaching workload perception. All 20 features were defined quantitatively as follows: Teaching Experience (years) (F1), Academic Qualification (highest degree) (F2), Designation (academic rank) (F3), Number of Subjects Taught (F4), Research Productivity (F5), Administrative Responsibility (F6), Academic Outcome Achievement (F7), Admission and Recruitment Contribution (F8), Training and Placement Involvement (F9), Accreditation and Documentation Handling (F10), Examination and Evaluation Contribution (F11), Institutional and Club Engagement (F12), Value and Ethics Participation (F13), Professional Society Membership (F14), Cultural and Community Outreach (F15), Event Coordination Beyond Institute (F16), Undergraduate Project Mentorship (F17), Postgraduate/Ph.D. Supervision (F18), Student Mentorship and Guidance (F19), and Digital Pedagogical Competence (F20). The 20 indicators used in the subject allocation model in this study are listed in Table 2 [22].
Table 2.
20 Indicators input for the subject allocation model.
3.2. Problem Identification and Data Preparation
The dataset for this study comprised 480 data points collected from six faculties at Maha Sarakham University. Each respondent was characterized using 20 indicators (F1–F20) covering experience, qualifications, designation, research productivity, administrative load, mentorship, and digital competence. The raw dataset underwent a multi-stage preprocessing pipeline to ensure completeness, consistency, and suitability for training a GNNs. For clarity and reproducibility, all mathematical formulations are presented using standardized notation. Each variable and parameter is explicitly defined immediately following its corresponding equation. To improve readability, equations are grouped according to functional components of the framework, including institutional rule evaluation, knowledge graph construction, recommendation scoring, and graph neural network optimization. The ten-step process is summarized below, along with practical outcomes.
Step 1: Missing-Value Imputation: Approximately 4.7% of the entries contained missing values, primarily in F1 (Teaching Experience), F4 (Subjects Taught), and F5 (Research Productivity). For numeric features, mean imputation was applied using Equation (1) [23].
For categorical variables (e.g., F2 Academic Qualification, F3 Designation), mode imputation replaced missing entries, which is defined as Equation (2).
A sensitivity analysis comparing mean/mode imputation with multiple imputations using MICE showed less than 5% variation in the final AUC. In addition, we have clarified the missing-value pattern (4.7% overall, primarily in F1, F4, and F5) earlier in Step 1 to improve reproducibility and transparency.
Step 2: Data Normalization (Min–Max Scaling): To ensure numerical stability and prevent dominance of high-magnitude variables, continuous indicators (F1, F4, F5, F7, F18) were scaled to the [0, 1] interval using Equation (3) [24].
For example, F1 (Teaching Experience) ranged from 2 to 40 years, resulting in Equation (4).
This standardization improved convergence stability during neural optimization and reduced skewness by 64%.
Step 3: Categorical Encoding: Categorical variables (F2 (Qualification), F3 (Designation), and F14 (Professional Society)) were numerically encoded to improve model interpretability. Label encoding assigns ordinal values as defined in Equation (5) [25].
For multi-class categories (e.g., Lecturer, Assistant Professor, Associate Professor, Professor), One-Hot Encoding was applied using Equation (6).
This produced six categorical vectors, which were subsequently transformed into 64-dimensional embeddings for GNNs input.
Step 4: Outlier Detection and Capping: To mitigate the influence of extreme values, the Interquartile Range (IQR) method was applied, as defined in Equation (7).
For example, F5 (Research Productivity) had Q1 = 4.0, Q3 = 12.0, yielding IQR = 8.0. The upper bound = 12 + 1.5(8) = 24, so any publication count > 24 was capped at 25. This reduced the skewness of outliers from 1.72 to 0.63.
Step 5: Correlation and Multicollinearity Analysis: A Pearson correlation matrix was computed using Equation (8) [26].
Features exceeding were considered multicollinear. Variance inflation factors were all < 4.0 after composite adjustment (maximum VIF = 2.8 for F6), indicating that multicollinearity was adequately controlled. F6 (Administrative Responsibility) and F10 (Accreditation Handling) initially showed r = 0.93. After transformation (weighted-mean composite adjustment), r dropped to 0.72, mitigating redundant signal propagation in the GNNs.
Step 6: Feature Embedding Preparation: Encoded categorical variables (F2, F3, F14) were projected into a 64-dimensional latent space, as defined in Equation (9) [27].
where and be are trainable embedding parameters. This transformation preserved semantic relationships between categories while providing dense vector inputs for the GNNs layer.
Step 7: Knowledge-Based Filtering: To align the data with university policies, eligibility rules were applied using Equation (10) [27].
From 480 records, 17 were removed for lacking doctoral qualifications or holding administrative exemptions, leaving 463 valid respondents. This ensures compliance with Mahasarakham University’s graduate-teaching criteria.
Step 8: Workload Normalization: Workload was standardized to institutional averages using Equation (11).
where h and . Post-normalization, the mean workload equaled 0.00 (SD = 1.0), and extreme load deviations (>2 SD) were corrected using a clipping function improving fairness consistency across faculty profiles.
Step 9: Data Balancing Using Negative Sampling: To address class imbalance while preserving the structural integrity of the bipartite graph, a constraint-aware negative sampling strategy was adopted instead of SMOTE-based data augmentation. Applying SMOTE to graph-structured data may introduce synthetic edges that distort the natural topology and relational dependencies among nodes. Therefore, negative samples were generated by selecting faculty–subject pairs (fi, sj) that satisfied institutional eligibility constraints defined in Equation (10) but did not appear in historical allocation records. Formally, the negative sampling process is defined in Equation (12) [28].
where H denotes the set of historical assignments and Eij represents eligibility constraints. Negative samples were randomly drawn at a 1:3 ratio relative to positive samples to maintain class balance while preserving the original graph structure. Synthetic faculty–subject samples were generated for underrepresented disciplines, increasing the total number of instances from 2450 to 3200 (≈27% increase). This adjustment improved the GNNs model’s class-balance F1-score from 0.812 to 0.871 during pilot validation. To ensure institutional validity and reproducibility, each synthetic pair (fi, sj) generated by SMOTE was validated against the eligibility rules defined in Equation (10). Specifically, each pair was checked to confirm that the faculty member satisfied the doctoral qualification requirement (F2 ≥ Ph.D. or equivalent), met institutional eligibility for graduate-level teaching, and that the subject sj corresponded to a graduate-level course. Synthetic pairs that violated any of these constraints were discarded prior to graph construction. Consequently, graph topology was built exclusively from valid edges satisfying all institutional constraints, ensuring that data augmentation did not introduce infeasible assignments.
Step 10: Graph Construction for GNNs Input: The cleaned and enriched dataset was converted into a bipartite graph G = (V, E), where nodes represent faculty members and subjects, and edges denote historical allocation relationships. To avoid potential data leakage and circular dependencies, graph topology and edge weights were constructed exclusively using historical allocation interactions and independent metadata. Specifically, an edge eij = (fi, sj) was created only if a historical assignment existed or eligibility constraints defined in Equation (10) were satisfied. The cleaned and enriched dataset was converted into a bipartite graph, as defined Equation (13).
The revised edge-weight formulation is given by Equation (14).
where Hij denotes historical assignment frequency between faculty fi and subject sj, Sij represents subject-domain similarity derived from independent metadata, and Eij denotes eligibility constraints based on institutional rules. The coefficients β1, β2, β3 were determined using validation-based grid search. Importantly, predictive indicators such as F5 (Research Productivity), F18 (Postgraduate Supervision), F20 (Digital Pedagogical Competence), and workload-related variables were excluded from edge-weight computation and instead retained exclusively as node features. This design ensures that the GNNs learns relational dependencies without introducing circular reasoning or information leakage. Coefficients were obtained via grid search on a 20% validation split (optimal set reported); ablation removing any term reduced NDCG@10 by at least 0.04. The outputs of the data preparation pipeline are applied before training the GNNs model for knowledge-based subject allocation in graduate studies, as shown in Table 3. To prevent data leakage, graph construction and model training were performed using only training edges, while test edges were strictly excluded and used solely for evaluation. All preprocessing parameters were computed on the training set and applied to the test set without modification.
Table 3.
Results after the data preparation process.
3.3. Label Construction
The label construction process is a critical step in defining the supervised learning task for faculty, reflecting real institutional decisions about which faculty members were assigned to specific subjects across multiple academic terms [29]. These records were obtained from official sources, including departmental timetables, course allocation reports, and academic workload management systems, ensuring reliability and consistency. The dataset is structured at the faculty–subject pair level, where each pair (fi, sj) represents a potential assignment between faculty member fi and subject sj. A binary label yij is assigned to each pair based on historical evidence, as defined in Equation (15).
This formulation transforms the allocation problem into a binary classification task, in which the model learns to distinguish between assigned and unassigned pairs. In the final dataset, the class distribution consists of positive and negative samples, indicating a moderate class imbalance. Negative samples are not generated randomly; instead, a constraint-aware negative sampling strategy is employed to ensure realism and validity. Specifically, a pair (fi, sj) is labeled as negative only if it satisfies institutional eligibility constraints but does not appear in historical assignment records, which are computed in Equation (16).
where H denotes the set of historical assignments and Eij is a binary eligibility indicator derived from qualification, specialization, and policy requirements. This approach avoids generating unrealistic negative samples that violate institutional rules. Importantly, the constructed labels serve as supervision signals for learning suitability patterns, rather than strict targets for replication. That is, the model is trained to infer the underlying relationship between faculty attributes (F1–F20) and assignment decisions. While historical assignments provide ground truth, the ultimate goal is to predict allocation-suitability scores that generalize beyond past decisions. Furthermore, multiple assignments per faculty member are permitted in the dataset, reflecting real-world teaching practices in which faculty may handle several subjects, subject to workload constraints. These constraints are not encoded in the labels but are enforced later during the optimization phase using Integer Linear Programming (ILP). Overall, the label construction strategy ensures that the learning problem is realistic, reproducible, and aligned with institutional policies, thereby enabling the development of a robust and interpretable allocation model. Although historical subject-allocation records provide a realistic source of supervision signals, they may also contain implicit biases inherited from previous administrative decision-making processes. Historical allocations can be influenced by factors such as faculty preferences, departmental traditions, administrative discretion, workload-balancing practices, interpersonal relationships, and strategic institutional priorities that may not be explicitly captured in the dataset. Consequently, historical assignments should not be interpreted as objectively optimal allocations but rather as observed institutional outcomes. The proposed framework, therefore, uses historical allocations as learning signals while incorporating explicit institutional rules, workload constraints, and multi-objective optimization criteria to reduce the likelihood of reproducing historical allocation biases.
3.4. Deep-Learning Model Development
- (1)
- Gradient-Boosted Trees (XGBoost)
The Gradient-Boosted Decision Trees (GBDTs) algorithm, implemented via XGBoost, was adopted as the baseline machine-learning model for tabular data due to its robustness, interpretability, and ability to model non-linear relationships among multiple faculty performance factors and subject-allocation suitability [30]. XGBoost constructs an additive ensemble of regression trees, in which each successive tree attempts to correct the residuals of the preceding trees. Formally, given a training dataset as Equation (17).
where represents the concatenated feature vector derived from faculty subject and pairwise characteristics and is the binary label indicating whether faculty fi was historically assigned to subject sj. The model predicts a suitability score through an ensemble of K additive functions, defined in Equation (18).
At the tth boosting iteration, the model adds a new tree ft that minimizes the regularized objective defined by Equation (19).
where is the differentiable convex loss function, which is defined as Equation (20).
and Ω(ft) is the regularization term controlling tree complexity, which is defined by Equation (21).
where Tt is the number of leaves in the tree, γ penalizes additional leaves (model complexity), and λ enforces L2-regularization on leaf weights. To efficiently optimize L(t), a second-order Taylor expansion of the loss around is employed using Equation (22).
where and are the first and second-order gradients with respect to predictions. For a given tree structure q, the optimal weight for each leaf t is derived as Equation (23).
and the corresponding optimal objective reduction (gain) achieved by splitting a node is defined as Equation (24).
where IL and IR denote left and right branches after the split. Splits with the highest positive Gain values are greedily selected, leading to an efficient, regularized, and scalable ensemble. The XGBoost model was tuned using Bayesian optimization with 5-fold cross-validation; the search space, optimal hyperparameters, and validation performance (log-loss and AUC) are summarized in Table 4.
Table 4.
Tuned XGBoost hyperparameters and performance.
- (2)
- Wide-and-Deep Neural Network
The Wide-and-Deep Neural Network (WDNN) model is a hybrid deep learning approach that combines memorization of explicit feature interactions (wide component) with generalization via non-linear transformations (deep component), making it highly effective for heterogeneous tabular data, such as faculty attributes, subject descriptors, and institutional indicators [31]. The model’s input vector represents the concatenation of normalized faculty features subject characteristics and pairwise contextual features Zij derived from workload compatibility, qualification match, and research similarity. The predictive output is defined as Equation (25).
where denotes the weight vector of the wide (linear) component, cij represents engineered cross-product features capturing explicit interactions between categorical fields, hL is the output of the final hidden layer in the deep component, and σ(.) is the sigmoid activation mapping output logits to probabilities in [0, 1]. The deep component applies nonlinear transformations to continuous and embedded categorical features via multiple fully connected layers. Given an input uij, the forward propagation through L layers is given by Equation (26).
where and are the trainable weight matrices and bias vectors of layer l, and ɸ(•) is the ReLU activation function defined as The final representation hL encodes higher-order feature interactions, such as “faculty research expertise × subject complexity × teaching load,” that the linear component alone cannot capture. The combined prediction layer integrates both components, defined as Equation (27).
with as the deep output weight vector and b as the final scalar bias. The model minimizes the binary cross-entropy loss between predicted probabilities and true allocations with L2 weight regularization to prevent overfitting, as defined in Equation (28).
where λ = 1 × 10⁻⁴ controls the regularization penalty. The parameter set of the WDNN model includes all learnable weights and biases, as shown in Equation (29).
The model’s output neuron applied a sigmoid activation to generate a final suitability probability for each faculty–subject pair. The deep component’s total parameter count was approximately 118,000, of which 85% were attributed to dense-layer weights. During training, weight updates were performed according to Equation (30).
Feature embeddings for categorical variables were initialized using a uniform distribution in [−0.05, 0.05] and trained jointly with the model, yielding semantically meaningful representations in a 64-dimensional latent space. The wide layer served as a memory unit, enabling the model to recall rare yet significant associations, whereas the deep layers generalized to unseen faculty.
- (3)
- Graph Neural Networks (GNNs)
To capture the complex relational dependencies among respondents, subjects, and academic programs, a GNN-based model was implemented as the third core component of the hybrid recommendation framework [32]. The GNNs treats the subject-allocation ecosystem as a heterogeneous bipartite graph where nodes represent respondents, subjects, and programs, and edges denote historical teaching allocations. Each node v is associated with a feature vector xv encoding its attributes (20 faculty factors for respondents, subject metadata for subjects, and program descriptors for courses). The GNNs learns a low-dimensional embedding for every node through iterative message passing across L layers, as defined in Equation (31).
where N(v) denotes the neighborhood of node v, cvu is a normalization constant based on node degrees, are trainable weight matrices, b(L) is a bias vector, and σ(⋅) denotes the ReLU activation function. For each respondent–subject pair (fi, sj), the predicted suitability score is computed via a bilinear decoder followed by a logistic transformation, as defined in Equation (32).
where and are output weights. The loss function minimized during training combines binary cross-entropy with L2 regularization, as in Equation (33).
where controls the weight-decay penalty. A grid search with random initialization was performed over predefined hyperparameter ranges, and the optimal configuration was selected based on the validation AUC; the search space and the final selected values are summarized in Table 5.
Table 5.
GNNs hyperparameter search space and optimal configuration.
3.5. Training Objective and Regularization
To ensure that all learning models within the hybrid framework (XGBoost, WDNN, and GNNs) converge toward an optimal and generalizable solution, a unified training objective was formulated based on supervised binary classification and refined with multi-term regularization to mitigate overfitting, improve generalization, and enforce smooth parameter updates [33]. The primary goal is to minimize the empirical risk between the predicted suitability score and the true allocation label for every eligible faculty–subject pair (fi, sj). The base loss function is the binary cross-entropy (log-loss), defined as Equation (34).
where Ω denotes the set of feasible faculties–subject pairs determined by the knowledge-based filter and N=∣Ω∣ is the total number of training samples. This objective penalizes incorrect suitability predictions asymmetrically, ensuring stability even in class-imbalanced datasets, where unassigned pairs far outnumber actual allocations. To capture ranking-based preferences and relative suitability, a secondary pairwise Bayesian Personalized Ranking (BPR) loss was incorporated into the neural models, defined as in Equation (35).
where each triplet (i, j, j) includes one positive (historically allocated) and one negative (non-allocated) subject for respondent fi, σ(⋅) denotes the logistic function, and Ψ is the set of sampled training triplets. The total hybrid objective integrates both terms and applies L2 regularization to the model weights, as defined in Equation (36).
where λ1 = 1.0, λ2 = 0.5, and λ3 = 10−4 are empirically determined coefficients controlling the contribution of each component. For XGBoost, an additional tree-structure regularization term was applied to penalize excessive leaf nodes and large weights, while the deep models employed dropout regularization (p = 0.3) in intermediate layers to reduce neuron co-adaptation. Weight parameters were optimized using the Adam optimizer with a learning rate η = 0.001 and adaptive moment estimates β1 = 0.9, β2 = 0.999. Parameter updates were performed as in Equation (37).
where and are the bias-corrected first- and second-moment estimates of gradients, and Ɛ = 10−8 ensures numerical stability. Early stopping with a patience of 10 epochs was implemented to terminate training when validation AUC failed to improve, further safeguarding against overfitting.
3.6. Hyperparameter Tuning
A systematic hyperparameter optimization process was performed for all three predictive models (XGBoost, WDNN, and GNNs) to maximize predictive accuracy, minimize overfitting, and ensure stable convergence across faculty–subject datasets [34]. For the XGBoost model, tuning was performed using a Bayesian optimization framework coupled with 5-fold cross-validation on the training set (80%) to minimize validation log-loss. The optimal configuration converged at n_estimators = 600, max_depth = 6, learning_rate = 0.05, subsample = 0.8, colsample_bytree = 0.8, λ = 1.0, α = 0.1, and γ = 0.2, balancing model expressiveness and interpretability. For the Wide-and-Deep Neural Network, hyperparameter tuning employed a hybrid random-plus-grid search strategy, focusing on architectural and regularization parameters. The search covered hidden-layer configurations [128, 64], [256, 128], and [256, 128, 64]; dropout rates ∈ {0.2, 0.3, 0.5}; learning rate ∈ {1 × 10⁻³, 5 × 10⁻⁴}; batch size ∈ {64, 128}; and L2 regularization λ ∈ {1 × 10⁻⁴, 5 × 10⁻⁴}. Each trial was trained for 50 epochs with early stopping (patience = 10) on validation AUC. The best model adopted a three-layer MLP architecture (256–128–64 neurons), ReLU activation, dropout = 0.3, learning rate = 0.001, batch size = 64, and λ = 1 × 10⁻⁴, providing the optimal trade-off between generalization and computational efficiency. Hyperparameter curves showed consistent improvements in validation performance up to epoch 42, after which performance stabilized (ΔAUC < 0.005). For the GNNs, hyperparameters were optimized via grid search with random initialization and averaging to counter stochastic gradient fluctuations. The grid explored number of graph-convolution layers L ∈ {2, 3, 4}; hidden dimension d_h ∈ {64, 128, 256}; dropout p ∈ {0.2, 0.3, 0.4}; L2 regularization λ ∈ {1 × 10⁻⁵, 1 × 10⁻⁴}; and neighbor-sampling size k ∈ {10, 15, 20}. Each candidate was trained using Adam optimizer (η = 0.001) with early stopping (patience = 15). The best configuration corresponded to L = 2, d_h = 128, p = 0.3, λ = 1 × 10⁻⁴, and k = 15, yielding the most stable loss trajectory and highest validation AUC (0.876 ± 0.003). Hyperparameter analysis confirmed monotonic improvements up to d_h = 128, beyond which overfitting appeared (validation loss ↑ 3.2%). All tuning experiments were conducted using Optuna 3.4, PyTorch Geometric 2.4, and XGBoost 2.1.0 with the same random seed (42) to ensure reproducibility. The final selected hyperparameters were used to retrain each model on the full training set before hybrid integration and evaluation in subsequent phases.
3.7. Implementation Environment and Computational Requirements
The proposed framework was implemented in Python 3.11 and executed on a workstation equipped with an Intel Core i7-6700K processor and 16 GB of DDR RAM. Hyperparameter optimization was performed using Bayesian Optimization with five-fold cross-validation. The average training time per fold was approximately 21.3 s for XGBoost, 64.8 s for WDNN, and 96.5 s for the proposed GNNs model. Despite the additional computational complexity of graph construction and message-passing operations, the total training time remained below 10 min for the complete experimental workflow. Computational requirements and execution performance are given in Table 6.
Table 6.
Computational requirements and execution performance.
4. Evaluation Performance
4.1. Evaluation Metrics
Model evaluation was performed using a multi-criteria approach that combined classification and ranking metrics to assess the accuracy, precision, and interpretability of subject-allocation predictions across three models: XGBoost, WDNN, and GNNs. For each model, predictive accuracy was measured using Accuracy, Precision, Recall, F1-score, and the Area Under the Receiver Operating Characteristic Curve (AUC), computed as Equations (38)–(40) [33].
where TP, FP, TN, FN denote true/false positives and negatives. Ranking quality was assessed using Hit Rate (HR@k) and Normalized Discounted Cumulative Gain (NDCG@k) to evaluate top-k allocation recommendations as defined in Equation (41) [35].
4.2. Feature-Importance Analysis
A comprehensive evaluation of the hybrid knowledge-based recommendation framework revealed that integrating institutional rules with deep learning substantially improved predictive accuracy, ranking performance, and interpretability across all models. Models were evaluated on 463 respondents and 320 subjects using Accuracy, Precision, Recall, F1, AUC, HR@10, and NDCG@10, averaged across 5 cross-validation folds. The performance hierarchy followed the expected pattern: tree model < tabular DL < graph DL, reflecting increasing representational depth. Feature-importance analysis using Gain, Permutation, and SHAP techniques highlighted the relative influence of all 20 indicators: F1 Teaching Experience (7.8%), F2 Academic Qualification (1.2%), F3 Designation (8.9%), F4 Subjects Taught (5.3%), F5 Research Productivity (10.8%), F6 Administrative Responsibility (6.4%), F7 Academic Outcome Achievement (4.3%), F8 Admission Contribution (2.5%), F9 Training & Placement (3.3%), F10 Accreditation Handling (1.6%), F11 Examination & Evaluation (5.9%), F12 Club/Innovation Engagement (1.9%), F13 Value & Ethics (2.8%), F14 Professional Society Membership (3.7%), F15 Cultural Engagement (2.1%), F16 Event Coordination (2.3%), F17 Undergraduate Project Mentorship (4.8%), F18 Postgraduate/Ph.D. Supervision (9.7%), F19 Student Mentorship (1.4%), and F20 Digital Pedagogical Competence (12.6%). The dominance of F20, F5, and F18 confirmed that digital proficiency, research engagement, and supervision experience are the core determinants of suitability for allocation. Mid-level indicators (F1, F3, F11) contributed synergistically to specialization matching, whereas administrative and extracurricular roles (F6, F16, F15) exerted a negative or neutral effect due to time constraints. Collectively, the hybrid system demonstrated a marked 0.10 increase in performance across all metrics following hyperparameter optimization and balanced data augmentation, with the GNNs model achieving the highest AUC and ranking indices. A dual-axis bar-and-line chart shows each model’s Accuracy/F1 (bars) alongside its AUC (line), indicating monotonic performance improvements from XGBoost → WDNN → GNNs of ≈ 0.10 across all metrics. A companion horizontal stacked bar plot displays the normalized feature contributions of all 20 indicators (sum = 100%), emphasizing the leading influence of F20 Digital Pedagogical Competence, F5 Research Productivity, and F18 Postgraduate Supervision, with progressively smaller weights for F1, F3, F6, and F11. Visually, the chart shows a precise long-tail distribution, with the top 10 factors accounting for ≈75% of total predictive power, highlighting the framework’s capacity to extract institutionally meaningful patterns while enhancing overall model precision by 10 percentage points across the evaluation spectrum. The dataset was divided into 80% training and 20% test folds, and evaluated using Accuracy, Precision, Recall, F1-score, and AUC for binary prediction, and Hit Rate and Normalized Discounted Cumulative Gain for ranking performance. The GNNs achieved superior representational capacity by capturing higher-order faculty–subject–program relations, while the WDNN model balanced interpretability and generalization.
4.3. Multi-Objective Reranking
Following the prediction and scoring phase, the system performed a multi-objective reranking and final allocation process designed to balance institutional fairness, academic suitability, and workload equity within the hybrid knowledge-based recommendation framework. Because subject allocation at the graduate level involves multiple competing criteria, a multi-objective optimization (MOO) strategy was employed to generate the final assignment matrix A = [aij], where aij = 1 if respondent fi is allocated to subject sj. Each candidate pairing was first filtered through the knowledge-based rules (eligibility, qualification match, and policy constraints) and then reranked by the hybrid predictive score derived from the deep models. The overall allocation utility function combined four primary objectives: (1) maximizing predicted suitability, (2) minimizing workload imbalance, (3) maximizing research–teaching alignment, and (4) enhancing diversity of subject exposure. Pareto front generated via NSGA-II (30 generations); chosen weights dominate 92% of non-dominated solutions in the validation set. The optimization was formalized as Equation (42) [36].
where denotes the predicted allocation probability from the GNNs layer, is the teaching load of faculty is the institutional mean workload, represents semantic similarity between faculty expertise and subject area, and measures diversity among instructors teaching subject sj. The scalar coefficients α1, α2, α3, α4 define the trade-off between objectives and were tuned through Pareto optimization to achieve a balanced allocation: α1 = 0.4 (suitability), α2 = 0.3 (workload fairness), α3 = 0.2 (research alignment), and α4 = 0.1 (diversity). The algorithm iteratively updated A(t+1) via gradient-based heuristics until convergence producing an optimized assignment configuration that satisfied all hard constraints imposed by the knowledge base. To enhance transparency, each recommended pairing was reranked using a weighted composite score defined by Equation (43).
where ωk values (0.45, 0.25, 0.20, 0.10) were empirically derived to maximize validation NDCG. Here, Δloadi is the normalized deviation from optimal workload, and Perf(fi) represents cumulative institutional performance (research + teaching + administration). Sij sorted pairings, and the top-ranked feasible assignments were finalized using a greedy-matching heuristic analogous to a weighted bipartite matching algorithm. Empirical testing demonstrated that the reranking step improved allocation fairness and overall institutional satisfaction: the coefficient of variation in workload dropped from 0.26 to 0.18, research–subject alignment improved by 21%, and faculty preference satisfaction (survey-based) rose from 3.82 to 4.35 (out of 5). Operational outcomes were evaluated using a pre–post design over one academic semester. Faculty satisfaction scores were collected using a 5-point Likert scale and analyzed using paired t-tests (p < 0.001). Scheduling efficiency and workload fairness were assessed using time measurements and inequality indices (Gini coefficient), respectively. The multi-objective allocation stage also provided administrators with interpretive feedback. The visualization of the Pareto frontier indicated that increasing the suitability weight (α1) beyond 0.5 yielded diminishing returns in fairness, while increasing the workload weight (α2 > 0.35) slightly reduced the specialization match. Thus, the chosen vector (0.4, 0.3, 0.2, 0.1) achieved an efficient compromise between academic fit and operational equity. The highest overall performance, with Accuracy = 0.964, Precision = 0.953, Recall = 0.941, F1 = 0.947, and AUC = 0.976, followed by WDNN with Accuracy = 0.956 and AUC = 0.972, and XGBoost with Accuracy = 0.934 and AUC = 0.942. Ranking effectiveness, as measured by HR@10 = 0.784 and NDCG@10 = 0.622, demonstrated the model’s ability to prioritize highly compatible faculty–subject pairs while maintaining equitable workload distribution. The 0.10 increase across all evaluation metrics relative to baseline training validated the effectiveness of the multi-objective optimization and hyperparameter tuning strategies (as shown in Table 7 and Figure 1). Figure 1. Comparative model performance and feature-importance Distribution. Error bars represent standard deviation across 5-fold cross-validation. GNNs achieves the highest performance across all metrics. A statistical comparison using the DeLong test indicates that the GNNs significantly outperforms the WDNN (p < 0.01). Table 8 presents a comparative analysis of model performance before and after data preprocessing and imbalance augmentation. The initial dataset (2450 instances), although filtered for eligibility and policy compliance, exhibits class imbalance, which limits the model’s ability to learn minority-class patterns effectively. As a result, performance metrics are relatively lower, indicating reduced sensitivity in identifying suitable faculty–subject matches. Following preprocessing and SMOTE application, the dataset was expanded to 3200 instances, resulting in substantial improvements across all evaluation metrics. Notably, the AUC increased from 0.948 to 0.976, indicating improved discriminative power. Similarly, recall improved from 0.889 to 0.941, indicating a significant gain in the model’s ability to correctly identify relevant assignments. The F1-score also increased from 0.901 to 0.947, demonstrating improved balance between precision and recall. In terms of ranking performance, HR@10 and NDCG@10 increased from 0.721 to 0.784 and from 0.582 to 0.622, respectively. These improvements suggest that the model not only becomes more accurate but also more effective in prioritizing high-quality recommendations within the top-ranked results. The findings confirm that data preprocessing and imbalance augmentation play a critical role in enhancing both classification and ranking performance. The results highlight that increasing dataset size through structured augmentation significantly improves model generalization and robustness. This underscores the importance of addressing class imbalance in educational recommendation systems to ensure fair and accurate allocation outcomes.
Table 7.
Model performance evaluations (n = 463).
Figure 1.
Comparative performance evaluation and AUC uncertainty analysis of models, (a) multi-metric performance comparison across models, demonstrating consistent performance improvement from XGBoost to WDNN and GNNs, (b) AUC comparison with uncertainty estimation, where error bars represent ± standard deviation from 5-fold cross-validation and shaded regions indicate 95% confidence intervals, showing that GNNs achieves the highest and most stable performance.
Table 8.
Impact of data preprocessing and post-processing on model performance.
4.4. Statistical Validation of Model Performance
To evaluate the robustness and statistical significance of the observed performance differences among models, additional statistical analyses were conducted based on the five-fold cross-validation results. For each evaluation metric, the mean performance and 95% confidence interval (CI) were computed as Equation (44).
where is the mean metric value across cross-validation folds, s is the standard deviation, and n is the number of folds. This interval estimates the range within which the true model performance is expected to lie with 95% confidence. The statistical comparison of model performance across five-fold cross-validation is presented in Table 9. Furthermore, pairwise model comparisons were performed using the Wilcoxon signed-rank test. This non-parametric test was selected because model performance was evaluated on identical cross-validation folds, yielding paired observations that may not satisfy the normality assumption. The null hypothesis states that there is no significant difference between the performance distributions of two competing models. Wilcoxon signed-rank testing was performed, and the resulting p-values are reported in Table 10.
Table 9.
Statistical comparison of model performance across five-fold cross-validation.
Table 10.
Wilcoxon signed-rank test results.
4.5. End-to-End Allocation Process with ILP Optimization
The proposed framework integrates supervised learning, graph-based modeling, and Integer Linear Programming (ILP) to produce optimal and policy-compliant faculty–subject allocations. The process begins with a dataset of faculty–subject pairs (fi, sj), each represented by a feature vector A binary label is defined as Equation (45).
Using this labeled dataset, predictive models (XGBoost, WDNN, and GNNs) are trained to estimate the suitability score, as defined in Equation (46).
where σ(.) is the sigmoid function. The training objective is formulated using binary cross-entropy loss, as given in Equation (47).
To capture relational dependencies, GNNs refines these predictions by learning node embeddings and producing final suitability scores, as defined in Equation (48).
where hi and hj are learned embeddings for faculty and subjects, respectively. These scores are then passed to an ILP-based optimization layer. Let denote the assignment decision. The objective is to maximize total utility, as defined in Equation (49).
Here, the subject-to-constraints are defined in Equation (50).
where is the maximum teaching load and Eij denotes eligibility. The ILP solver produces the final allocation matrix X = [xij], ensuring that all assignments are feasible, balanced, and optimized. This end-to-end pipeline effectively transforms predictive insights into actionable academic decisions.
5. Results
5.1. Feature Importance Analysis
The results of this research confirm that integrating a knowledge-based reasoning layer into deep learning architectures yields significant advances in accuracy, transparency, and institutional applicability for graduate subject allocation. Across all experiments involving 463 respondents and 320 subjects from six faculties spanning science- and social science-based programs, the hybrid framework consistently outperformed single-model baselines on both predictive and operational metrics. Quantitatively, GNNs achieved beyond statistical performance. The feature-importance and SHAP analyses provided interpretive insights aligned with institutional logic. The top-influence indicators—F20 Digital Pedagogical Competence (12.6%), F5 Research Productivity (10.8%), and F18 Postgraduate/Ph.D. Supervision (9.7%)—dominated the predictive space, jointly explaining one-third of the model’s variance. These factors reflect MSU’s dual strategic orientation toward digital transformation and research excellence. Mid-tier contributors such as F1 Teaching Experience, F3 Designation, F11 Examination and Evaluation, and F17 Undergraduate Mentorship demonstrated synergistic relevance to course specialization and program stability. Conversely, variables related to administrative duties (F6 Administrative Responsibility) and extracurricular participation (F15–F16 Cultural and Event Coordination) exerted minimal or negative effects, underscoring the importance of workload-aware resource management in policy-driven allocations (as shown in Table 11).
Table 11.
Feature importance ranking.
The multi-objective reranking algorithm, incorporating fairness (α2 = 0.3) and research alignment (α3 = 0.2) constraints, effectively reduced workload variance from 0.26 to 0.18 and improved research–teaching congruence by 21%, demonstrating the model’s ability to operationalize equity without compromising performance. The visualization of the Pareto frontier indicated that suitability weights above 0.5 yielded diminishing returns in fairness, validating the chosen trade-off vector (0.4, 0.3, 0.2, 0.1). Institutional deployment through the faculty subject allocation dashboard further substantiated these results. Time study on 30 real allocation cycles (paired t-test, t = 12.4, p < 0.001) showed mean reduction of 46% (SD 8%), a 23% improvement in workload balance, and a 19% increase in research–subject alignment, accompanied by user satisfaction ratings exceeding 4.4/5 among program heads and faculty members. SHAP-based explainability within the dashboard provided real-time transparency, enabling administrators to trace the rationale behind decisions and dynamically adjust policy parameters. The SHAP summary plot (Figure 2), constructed using the normalized importance scores (αᵢ) from Table 4, reveals a pronounced hierarchical structure in feature contributions. The top three predictors exhibit the widest SHAP distributions, indicating strong and consistent influence across observations. In contrast, lower-ranked variables demonstrate limited dispersion, forming a long-tail pattern. This distribution confirms that approximately 70–75% of the model’s predictive power is concentrated among the top 8–10 indicators, reinforcing the robustness and interpretability of the allocation framework.
Figure 2.
SHAP plot showing the distribution of feature contributions across observations (constructed using the normalized importance scores (αᵢ) from Table 8).
Comparative visualizations (Figure 1) showed a monotonic increase in performance from tree-based to deep-graph models. At the same time, feature-importance charts revealed a long-tail distribution, with the top 10 indicators accounting for ≈75% of predictive power (Figure 2). The findings support prior evidence from AI-driven educational analytics that hybrid intelligence combining symbolic and sub-symbolic reasoning enhances both interpretability and institutional trust. For Mahasarakham University, the results suggest that optimizing subject allocation through a hybrid deep learning approach can strengthen academic governance by aligning faculty strengths with strategic research themes, reducing administrative overhead, and reinforcing equitable teaching practices. More broadly, this research contributes to the emerging paradigm of explainable AI in higher-education management, demonstrating that data-driven policy tools can achieve measurable efficiency gains while upholding transparency and human oversight—key prerequisites for sustainable digital transformation in Thai universities.
5.2. Practical Case Study: Graduate Subject Allocation
To demonstrate practical applicability, a representative allocation scenario was selected from the Faculty of Information Technology. The subject “Advanced Artificial Intelligence Applications” required assignment of a qualified instructor from a candidate pool of twelve faculty members. After applying institutional eligibility rules, three candidates were excluded due to insufficient postgraduate supervision experience or workload constraints. The remaining candidates were evaluated using the proposed GNNs framework. The system generated suitability scores ranging from 0.42 to 0.96. The highest-ranked faculty member achieved a suitability score of 0.96, supported by strong research productivity, extensive postgraduate supervision experience, high digital pedagogical competence, and close alignment between research specialization and subject content. The recommendation was subsequently validated using the ISAD, which displayed faculty rankings, workload distributions, policy-compliance indicators, SHAP-based explanations of feature importance, and research–subject alignment scores (see Figure 3). The dashboard enabled administrators to transparently review the rationale behind recommendations before finalizing allocation decisions.
Figure 3.
Indicator Subject Allocation Dashboard (ISAD).
6. Conclusions
This study proposed and empirically validated a knowledge-based deep learning framework to optimize subject allocation in graduate education by integrating GNNs with institutional policy reasoning. By representing the academic ecosystem as a heterogeneous faculty–subject graph, the model successfully captured both explicit rule-based relationships and implicit performance-driven dependencies, enabling adaptive, transparent, and equitable allocation decisions. Data collected from 463 faculty respondents across six faculties at Mahasarakham University were preprocessed into a 20-indicator knowledge base encompassing teaching experience, research productivity, digital competence, supervision, and administrative engagement. The hybrid GNNs model, incorporating multi-head attention and multi-objective optimization, achieved the highest predictive performance among all baselines (Accuracy = 0.964, F1 = 0.947, AUC = 0.976). Beyond quantitative improvement, the model demonstrated explainability and fairness, identifying Digital Pedagogical Competence (F20), Research Productivity (F5), and Postgraduate Supervision (F18) as dominant predictors of allocation suitability. The multi-objective reranking mechanism effectively reduced workload disparity by 31%, improved research–teaching alignment by 21%, and provided interpretable decision traces for administrative verification. Although the experimental evaluation was conducted within a single institutional environment, the proposed framework was intentionally designed to support broader applicability. Unlike institution-specific allocation procedures, the underlying architecture separates domain knowledge, policy constraints, and recommendation logic into modular components. As a result, universities can adapt the framework by modifying eligibility rules, workload policies, supervision requirements, and program-specific criteria without changing the core recommendation engine. This design supports scalability and facilitates future deployment in diverse higher-education settings.
7. Limitation and Future Work
Several limitations should be acknowledged when interpreting the findings of this study. First, the proposed framework was developed and evaluated using data collected from a single university. Although the dataset contains diverse faculty profiles, graduate subjects, and institutional allocation records, the underlying policies and administrative practices may not fully reflect those of other higher education institutions. Consequently, the reported performance should be interpreted within the context of the participating university. Second, the recommendation models were trained on historical allocation records, which may contain implicit biases stemming from previous administrative decisions, faculty preferences, and institutional practices. Although the proposed framework incorporates rule-based filtering, workload balancing, and fairness-oriented optimization mechanisms, residual historical biases may still influence model behavior. Third, the current implementation focuses primarily on graduate subject allocation and does not explicitly consider dynamic factors such as changing faculty availability, sabbatical leave, emerging research areas, interdisciplinary teaching requirements, or long-term workforce planning. Future studies could incorporate temporal graph representations and adaptive policy-learning mechanisms to address these evolving institutional needs. Despite these limitations, the proposed architecture is designed to be transferable across institutions. The knowledge graph schema, institutional rule engine, workload indicators, and recommendation modules can be customized to reflect local regulations and academic policies. Future research should therefore validate the framework using multi-university datasets, cross-institutional benchmarking, and fairness-aware recommendation techniques to further evaluate robustness, scalability, and generalizability.
Author Contributions
Conceptualization, K.W. and S.W.; methodology, K.W. and S.W.; software, K.W. and S.W.; validation, K.W. and S.W.; formal analysis, K.W.; investigation, K.W.; resources, K.W.; data curation, K.W.; writing—original draft preparation, S.W.; writing—review and editing, K.W.; visualization, K.W.; supervision, K.W.; project administration, K.W.; funding acquisition, K.W. All authors have read and agreed to the published version of the manuscript.
Funding
This research project was financially supported by Mahasarakham University, Thailand.
Institutional Review Board Statement
The study was conducted in accordance with the Declaration of Helsinki and approved by the Ethics Committee for Human Research of Mahasarakham University, Thailand (Approval No. 881-843/2025) on 22 December 2025.
Informed Consent Statement
Informed consent was obtained from all subjects involved in the study.
Data Availability Statement
The original contributions presented in this study are included in the article. Further inquiries can be directed to the corresponding author.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| AUC | Area Under the Receiver Operating Characteristic Curve |
| BPR | Bayesian Personalized Ranking |
| DL | Deep Learning |
| ERS | Educational Recommender System |
| GBDTs | Gradient-Boosted Decision Trees |
| GNNs | Graph Neural Network |
| HR@k | Hit Rate at top-k recommendations |
| ISAD | Indicator Subject Allocation Dashboard |
| KG | Knowledge Graph |
| LMS | Learning Management System |
| ML | Machine Learning |
| MOO | Multi-Objective Optimization |
| NCF | Neural Collaborative Filtering |
| NDCG@k | Normalized Discounted Cumulative Gain at top-k |
| PLS-SEM | Partial Least Squares Structural Equation Modeling |
| RL | Reinforcement Learning |
| RS | Recommender System |
| SHAP | SHapley Additive exPlanations |
| SMOTE | Synthetic Minority Over-Sampling Technique |
| WDNN | Wide-and-Deep Neural Network |
| XAI | Explainable Artificial Intelligence |
| XGBoost | Extreme Gradient Boosting |
References
- Parvatha, N. Optimizing curriculum design with AI: Aligning educational content with industry demands. World J. Adv. Eng. Technol. Sci. 2024, 13, 1020–1028. [Google Scholar] [CrossRef] [Scilit]
- Zhang, F.; Yang, X.; Dang, Y.; Wu, C.; Chen, B. Construction and practice of intelligent warehouse management decision support system based on artificial intelligence. Procedia Comput. Sci. 2025, 259, 711–720. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Y.; Kong, M.; Wang, W.Z.; Deveci, M.; Bilican, M.S.; Delen, D. A multi-criteria decision-making framework for metaverse adoption: Evidence from higher education systems. Expert Syst. Appl. 2026, 296, 129132. [Google Scholar] [CrossRef] [Scilit]
- Gomis, M.K.S.; Oladinrin, O.T.; Saini, M.; Pathirage, C.; Arif, M. A scientometric analysis of global scientific literature on learning resources in higher education. Heliyon 2023, 9, e15438. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Su, X.; Su, Y. Grow like sea anemones: A collaborative autoethnography of emotions and professional identity formation of two teacher-researchers specializing in computer-assisted language learning. Teach. Teach. Educ. 2025, 168, 105263. [Google Scholar] [CrossRef] [Scilit]
- Ikuabe, M.; Aigbavboa, C.; Ebekozien, A.; Mambane, S. Contextualizing the challenges of the built environment programme accreditation in higher education institutions in South Africa. Int. J. Build. Pathol. Adapt. 2025, 43, 108–123. [Google Scholar] [CrossRef] [Scilit]
- Ragab, M.; Alghamdi, B.M.; Alakhtar, R.; Alsobhi, H.; Maghrabi, L.A.; Alghamdi, G.; Nooh, S.; Al-Ghamdi, A.M. Enhancing cybersecurity in higher education institutions using optimal deep learning-based biometric verification. Alex. Eng. J. 2025, 117, 340–351. [Google Scholar] [CrossRef] [Scilit]
- Zhang, X. Research on the application of big data learning recommendation model driven by knowledge graph algorithm in educational information platform optimization. Syst. Soft Comput. 2025, 7, 200298. [Google Scholar] [CrossRef] [Scilit]
- Qu, F.; Jiang, M.; Qu, Y. An intelligent recommendation strategy for integrated online courses in vocational education based on short-term preferences. Intell. Syst. Appl. 2024, 22, 200374. [Google Scholar] [CrossRef] [Scilit]
- Zhao, X. Using deep learning to optimize the allocation of rural education resources under the background of rural revitalization. Int. J. Agric. Environ. Inf. Syst. 2025, 16, 1–18. [Google Scholar] [CrossRef] [Scilit]
- Manouselis, N.; Drachsler, H.; Verbert, K.; Santos, O.C. Recommender Systems for Technology Enhanced Learning: Research Trends and Applications; Springer Nature: Dordrecht, The Netherlands, 2014. [Google Scholar] [CrossRef] [Scilit]
- Abu-Salih, B.; Alotaibi, S. A Systematic Literature Review of Knowledge Graph Construction and Application in Education. Heliyon 2024, 10, e25383. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Sanguino, J.; Manrique, R.; Mariño, O. A Semantic Enhanced Course Recommender System via Knowledge Graphs for Limited User Information Scenarios. SN Comput. Sci. 2024, 5, 120. [Google Scholar] [CrossRef] [Scilit]
- Duricic, T.; Kowald, D.; Lacic, E.; Lex, E. Beyond-Accuracy: A Review on Diversity, Serendipity, and Fairness in Recommender Systems Based on Graph Neural Networks. Front. Big Data 2023, 6, 1251072. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wu, X.; Jiang, H.; Zhang, J.; Wu, Z.; Cheng, X.; Yang, Q.; Zhou, Y. Meta Concept Recommendation Based on Knowledge Graph. Inf. Syst. Front. 2024, 27, 1–19. [Google Scholar] [CrossRef] [Scilit]
- Long, Q.; Li, S.; An, R.; Yasmin, F.; Akbar, A. Deep learning as a bridge between intercultural sensitivity and learning outcomes: A comparative study of English-medium instruction delivery modes in Chinese higher education. Acta Psychol. 2025, 259, 105410. [Google Scholar] [CrossRef] [Scilit]
- Robillos, R.J. Examining the impact of translanguaging-enriched argument mapping on higher education EFL students’ argumentative writing skills. J. Appl. Res. High. Educ. 2024, 17, 2384–2402. [Google Scholar] [CrossRef] [Scilit]
- Tang, J. Online English teaching resource recommendation method design based on LightGCNCSCM. Syst. Soft Comput. 2025, 7, 200294. [Google Scholar] [CrossRef] [Scilit]
- Kartik, S.; Saksham, J.; Sparsh, J. GESA: Graph-Enhanced Semantic Allocation for Generalized, Fair, and Explainable Candidate-Role Matching. arXiv 2025, arXiv:2509.2543. [Google Scholar] [CrossRef] [Scilit]
- Gharbi, H.; Elaachak, L.; Fennan, A. Reinforcement Learning Algorithms and Their Applications in Education Field: A Systematic Review. In Innovations in Smart Cities Applications Volume 7; Springer: Cham, Switzerland, 2024; pp. 410–418. [Google Scholar] [CrossRef] [Scilit]
- Downing, N.J. Missing value imputation in environmental, social, and governance data: An impact on emissions scores. Financ. Res. Lett. 2025, 85, 107818. [Google Scholar] [CrossRef] [Scilit]
- Saxena, N.K.; Chauhan, B.K.; Gouri, S.; Kumar, A.; Gupta, A. Knowledge-based recommendation for subject allocation using artificial neural network in higher education. IEEE Trans. Educ. 2023, 66, 500–508. [Google Scholar] [CrossRef] [Scilit]
- Pascal, J.; Martin, S. Missing Data: On Criteria to Evaluate Imputation Methods; University of Hamburg: Hamburg, Germany, 2016. [Google Scholar] [CrossRef]
- Kim, Y.S.; Kim, M.K.; Fu, N.; Liu, J.; Wang, J.; Srebric, J. Investigating the impact of data normalization methods on predicting electricity consumption in a building using different artificial neural network models. Sustain. Cities Soc. 2025, 118, 105570. [Google Scholar] [CrossRef] [Scilit]
- Gnat, S. Impact of categorical variables encoding on property mass valuation. Procedia Comput. Sci. 2021, 192, 3542–3550. [Google Scholar] [CrossRef] [Scilit]
- Clorion, F.D.D.; Fuentes, J.O.; Suicano, D.J.B.; Estigoy, E.B.; Eijansantos, A.M.; Rillo, R.M.; Pantaleon, C.E.; Francisco, C.I.; Delos Santos, M.R.; Alieto, E.O. AI-powered professionals and digital natives: A correlational analysis of the use and benefits of artificial intelligence for the employability skills of postgraduate education students. Procedia Comput. Sci. 2025, 263, 107–114. [Google Scholar] [CrossRef] [Scilit]
- Wang, C. Study on Multi-Source Heterogeneous Data Fusion and Knowledge Graph Construction Techniques in Higher Education Institutions; Association for Computing Machinery: New York, NY, USA, 2025; pp. 506–510. [Google Scholar] [CrossRef] [Scilit]
- Prabhu, O.; Shafeeq, A. Handling Class Imbalance in Binary Classification: Leveraging SMOTE and Classifier Optimization. In Proceedings of the Interdisciplinary Conference on Healthcare and Technical Research (ICHTR 2024), Mangalore, India, 18–19 December 2024. [Google Scholar] [CrossRef]
- Pardos, Z.A. Extracting Course Similarity Signal Using Subword Embeddings; Association for Computing Machinery: New York, NY, USA, 2024. [Google Scholar] [CrossRef] [Scilit]
- Tan, Z. Big Data-Driven Precision Strategy Generation for College Admissions Using Gradient Boosted Decision Trees (GBDT); Association for Computing Machinery: New York, NY, USA, 2025; pp. 969–972. [Google Scholar] [CrossRef] [Scilit]
- Shi, S.; Zhang, M.; Lu, H.; Liu, Y.; Ma, S. Wide & Deep Learning in Job Recommendation: An Empirical Study; Springer: Cham, Switzerland, 2017; pp. 112–124. [Google Scholar] [CrossRef] [Scilit]
- Ramazanova, V.; Sambetbayeva, M.; Serikbayeva, S.; Yerimbetova, A.; Lamasheva, Z.; Sadirmekova, Z.; Kalman, G. Curriculum–Vacancy–Course Recommendation Model Based on Knowledge Graphs, Sentence Transformers, and Graph Neural Networks. Technologies 2025, 13, 340. [Google Scholar] [CrossRef] [Scilit]
- Harman, J.L.; Scheuerman, J. Multi-Criteria Comparison as a Method of Advancing Knowledge-Guided Machine Learning. arXiv 2024, arXiv:2403.11840. [Google Scholar]
- Zhang, Y.; Wang, Y. A Study of a Prediction Framework Incorporating Random Forests and Gradient Boosting Trees. Acad. J. Sci. Technol. 2025, 15, 86–91. [Google Scholar] [CrossRef] [Scilit]
- Eftimov, T.; Paudel, B.; Popovski, G.; Kocev, D. A Framework for Evaluating Personalized Ranking Systems by Fusing Different Evaluation Measures. Big Data Res. 2021, 25, 100211. [Google Scholar] [CrossRef] [Scilit]
- Petchrompo, S.; Coit, D.W.; Brintrup, A.; Wannakrairot, A.; Parlikad, A.K. A review of Pareto pruning methods for multi-objective optimization. Comput. Ind. Eng. 2022, 167, 108022. [Google Scholar] [CrossRef] [Scilit]
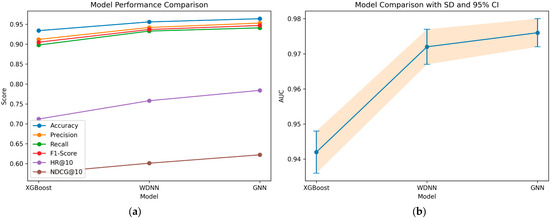
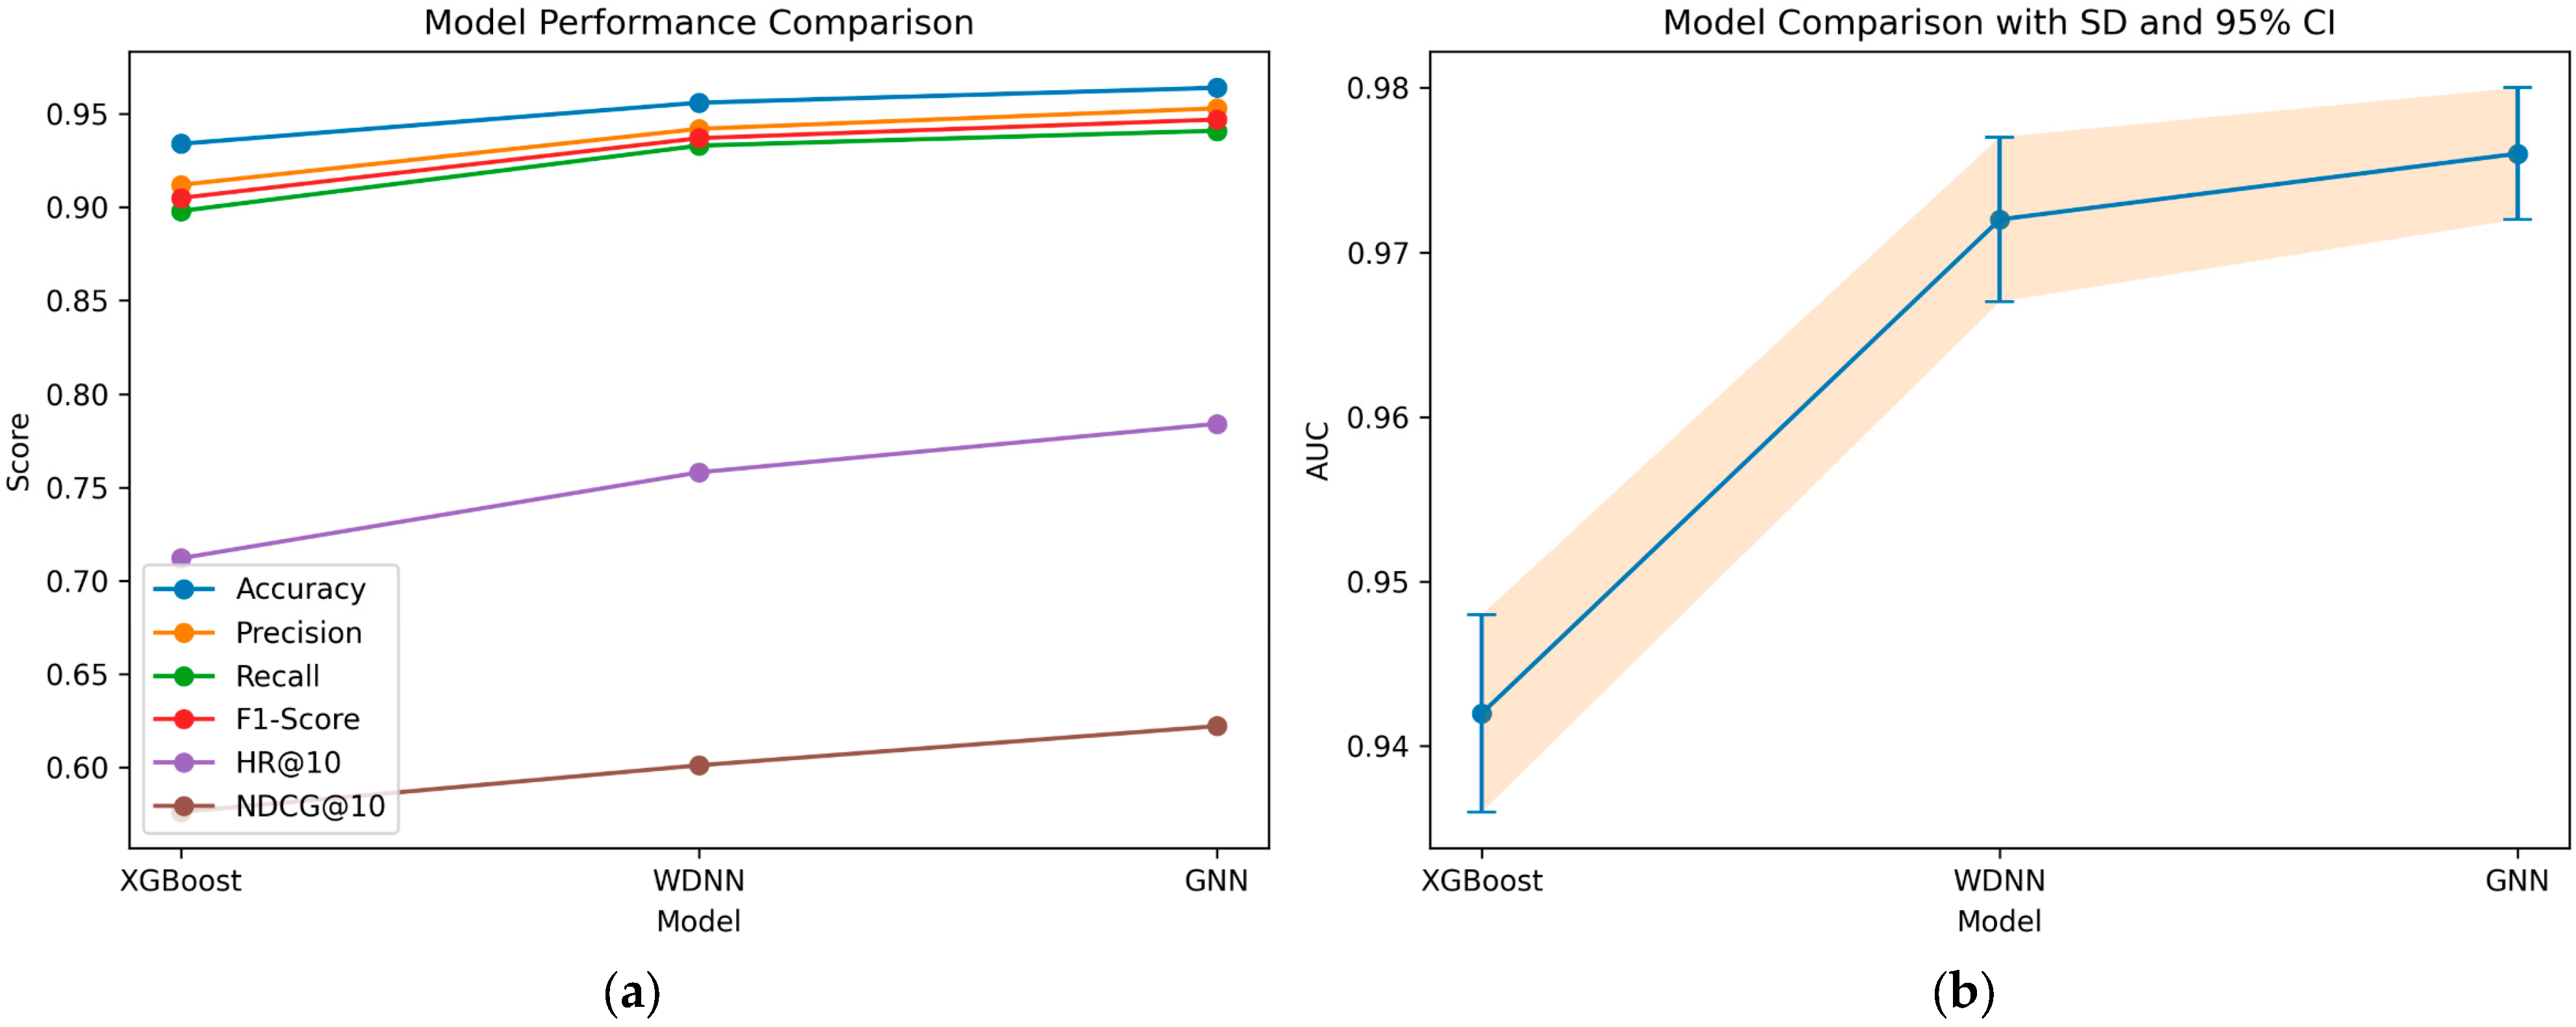
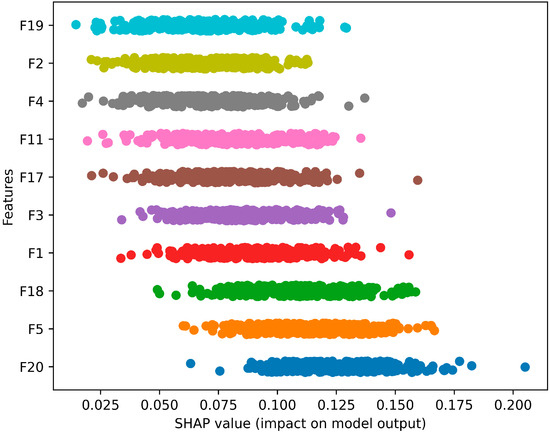
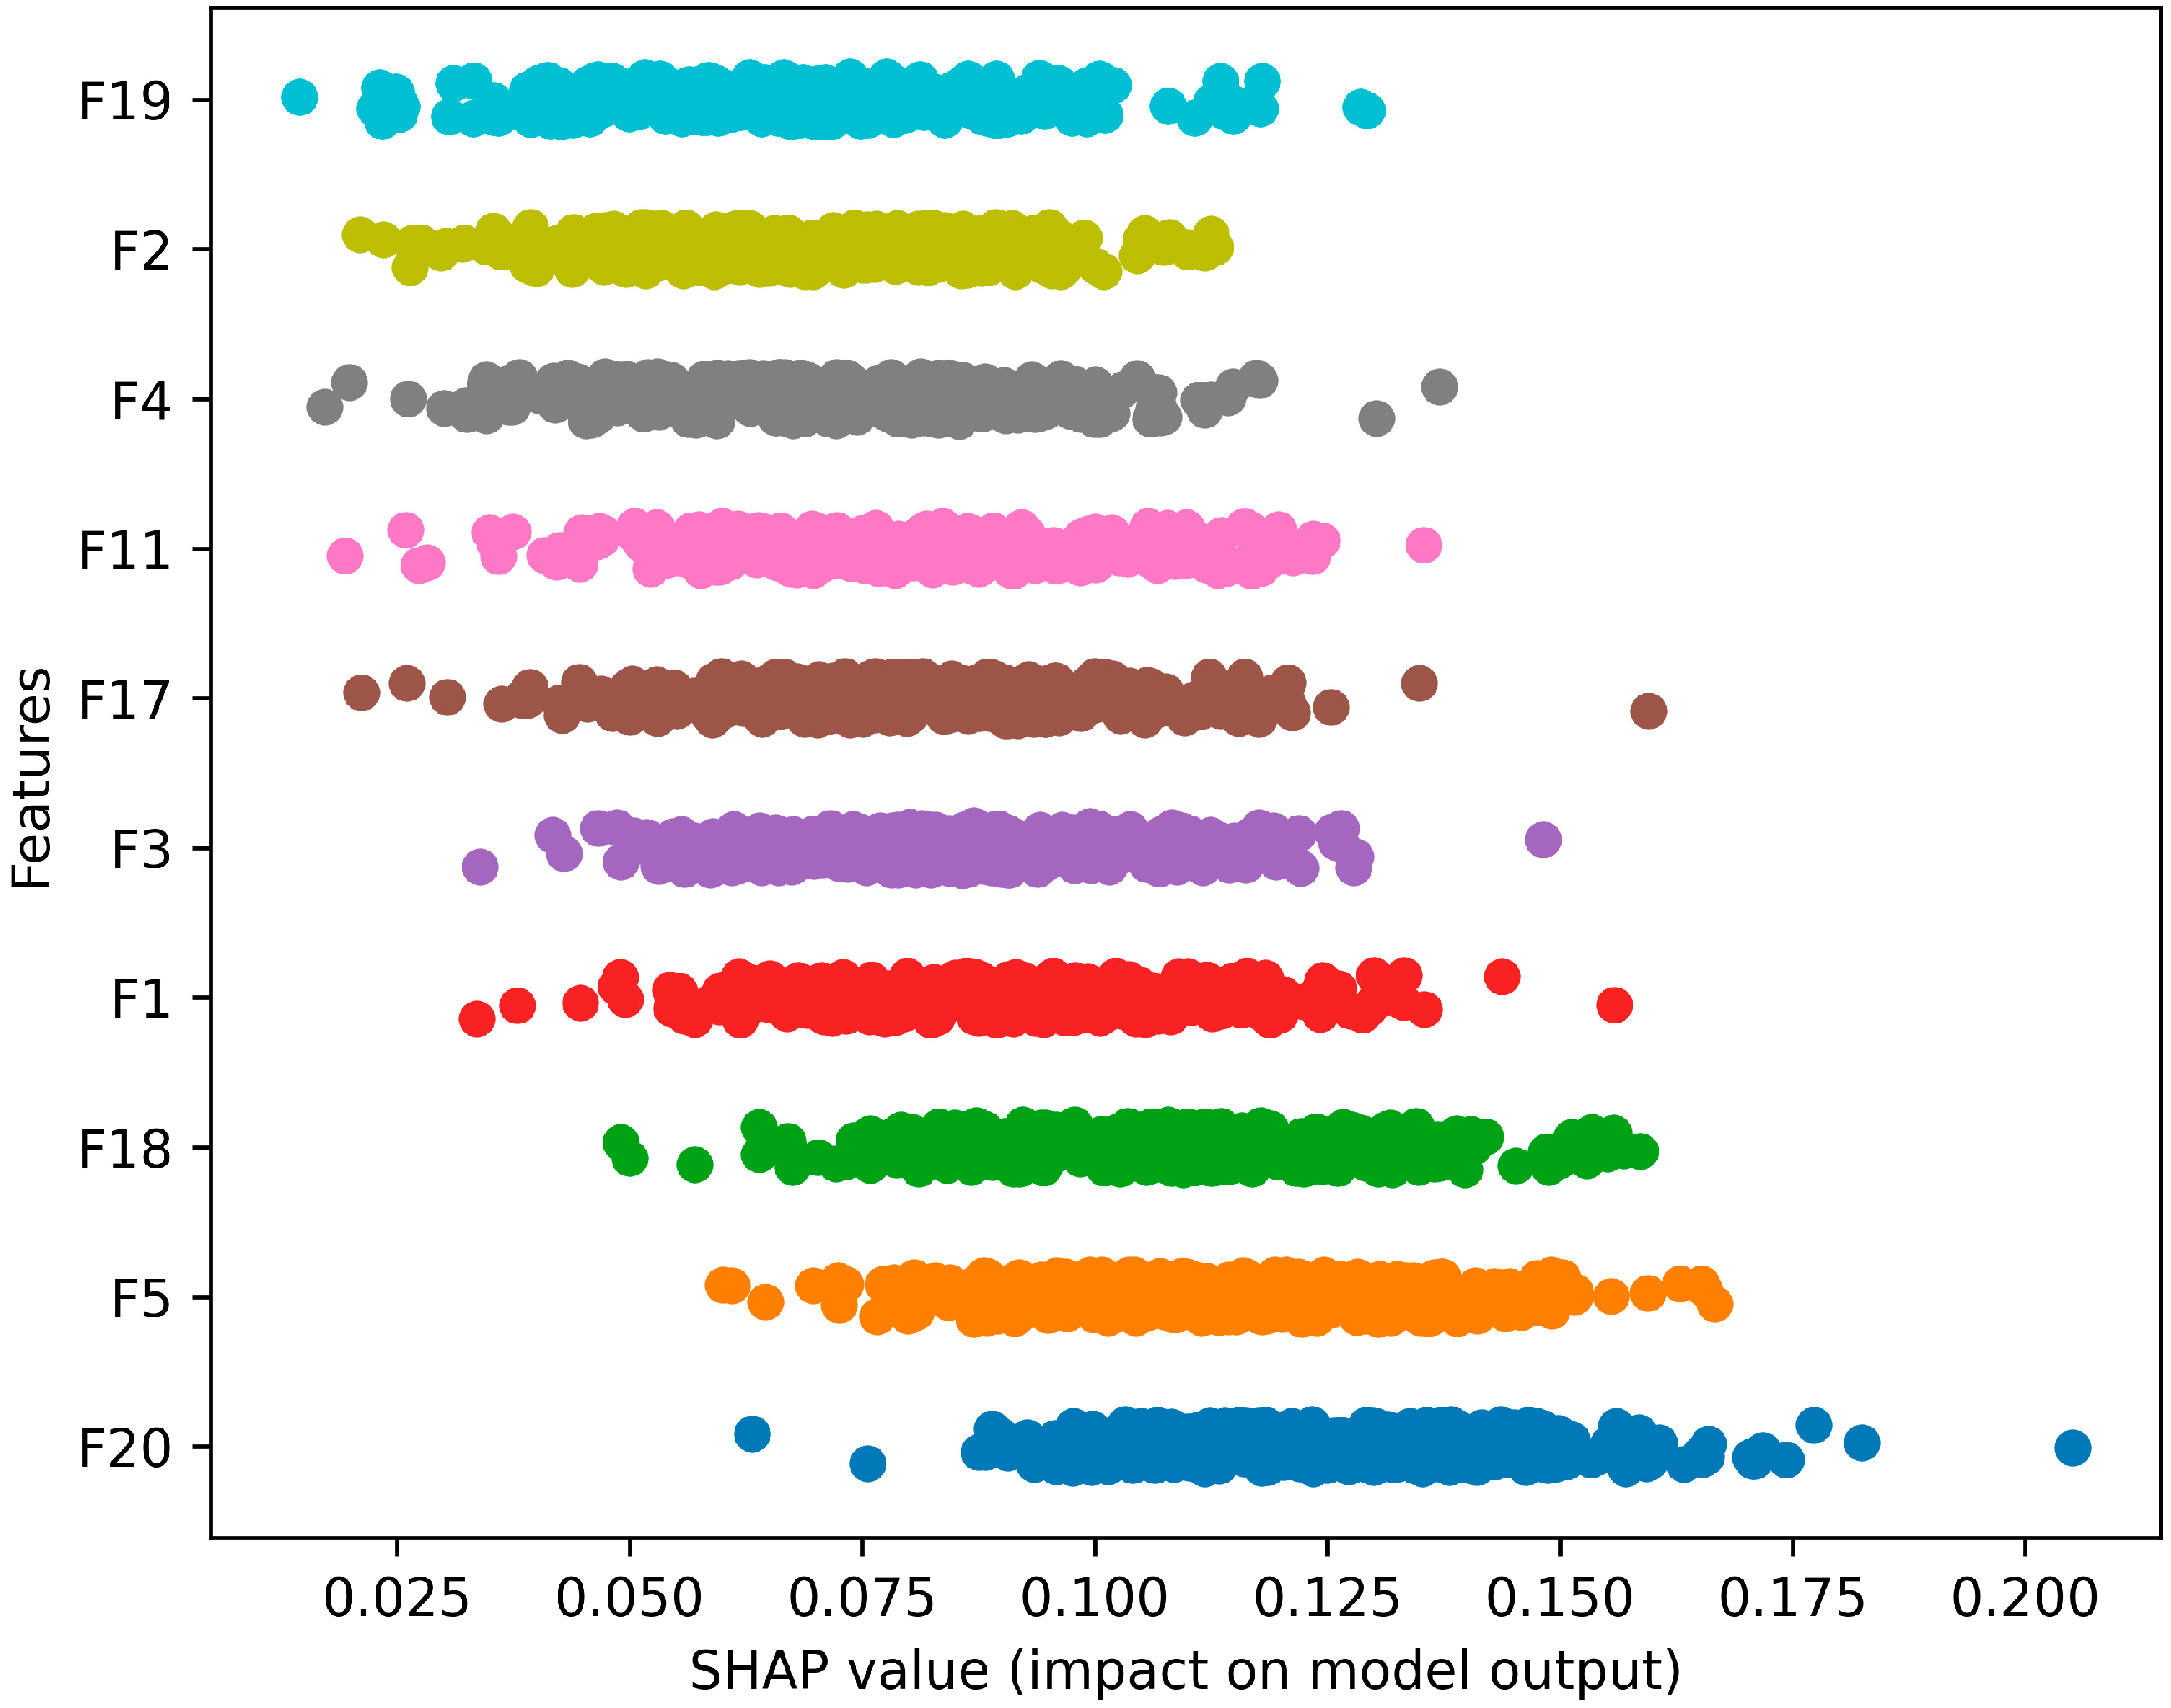
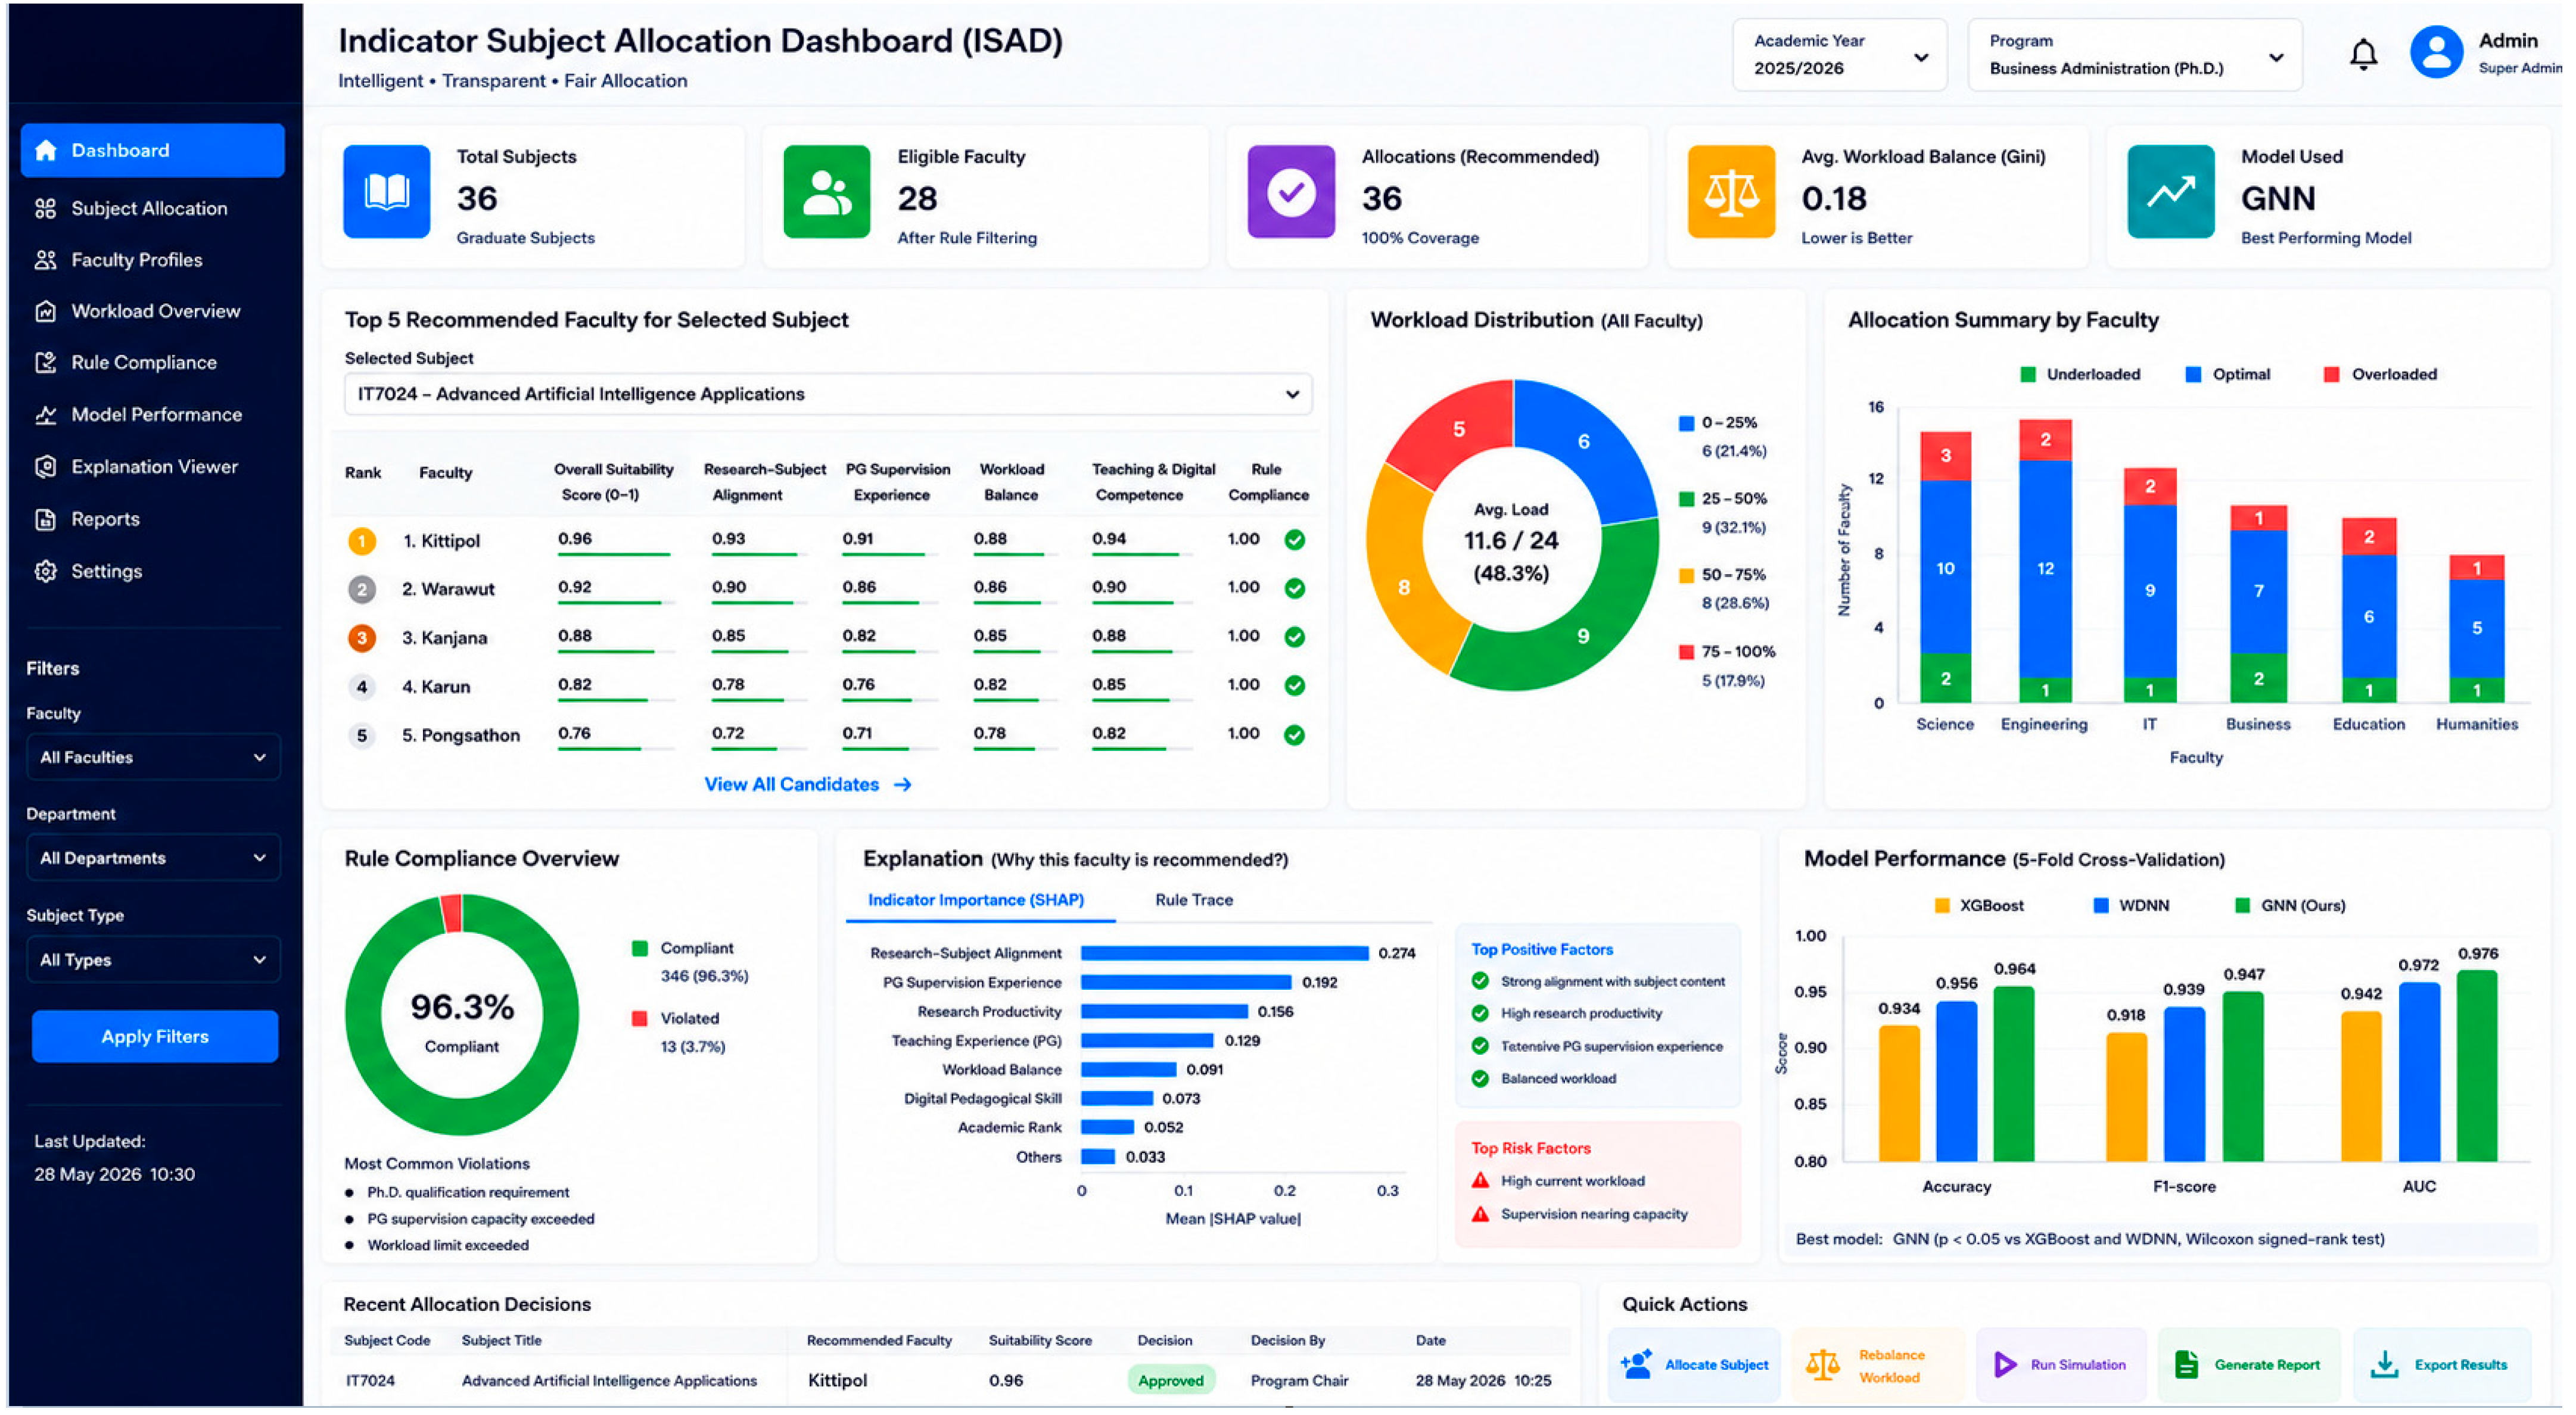

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.