


Abstract
The intricate and multifaceted nature of diabetes disrupts the body’s crucial glucose processing mechanism, which serves as a fundamental energy source for the cells. This research aims to predict the occurrence of diabetes in individuals by harnessing the power of machine learning algorithms, utilizing the PIMA diabetes dataset. The selected algorithms employed in this study encompass Decision Tree, K-Nearest Neighbor, Random Forest, Logistic Regression, and Support Vector Machine. To execute the experiments, two software tools, namely Waikato Environment for Knowledge Analysis (WEKA) version 3.8.1 and Python version 3.10, were utilized. To evaluate the performance of the algorithms, several metrics were employed, including true positive rate, false positive rate, precision, recall, F-measure, Matthew’s correlation coefficient, receiver operating characteristic area, and precision–recall curves area. Furthermore, various errors such as Mean Absolute Error, Root Mean Squared Error, Relative Absolute Error, and Root Relative Squared Error were examined to assess the accuracy of the models. Upon conducting the experiments, it was observed that Logistic Regression outperformed the other techniques, exhibiting the highest precision of 81 percent using Python and 80.43 percent using WEKA. These findings shed light on the efficacy of machine learning in predicting diabetes and highlight the potential of Logistic Regression as a valuable tool in this domain.
1. Introduction
Diabetes is a complicated and complex medical illness that has an impact on how the body utilizes glucose, a form of sugar that is the body’s primary fuel source. When our body is unable to create insulin or is unable to use the insulin that is produced by our bodies, diabetes results. According to statistics from 2017, 425 million people worldwide have diabetes. Diabetes causes 2 to 5 million deaths worldwide each year. By 2045, it is projected to grow to 629 million [1,2]. Type 1 diabetes, Type 2 diabetes, and gestational diabetes are the three primary subtypes of diabetes, which are categorized according to their underlying causes and physical effects.
Type 1 IDDM (Insulin-Dependent Diabetes Mellitus), also known as Type 1 diabetes, occurs when the body is unable to produce sufficient insulin, leading to a dependence on insulin injections for patients with this condition.
Type 2 is otherwise called Non-Insulin-Subordinate Diabetes Mellitus (NIDDM). This kind of diabetes is caused when the body’s cells cannot utilize insulin appropriately.
Type 3 is called gestational diabetes, which is the aftereffect of an expansion in glucose levels during incubation. These pregnant women have not been diagnosed with any kind of diabetes before. There are long-term complications associated with diabetes. Diabetes can likewise prompt a higher risk of different medical conditions.
Data mining is the process of finding insights into data, which helps in the prediction of an event before it happens. This technique is used to find some useful information from the raw data provided. If these techniques are accurately analyzed and applied to datasets, they can predict events when appropriate algorithms are used on training and testing datasets. In the previous paper we studied and reviewed, the diabetes prediction system required a small dataset [3], whereas the Pima Indians Diabetes Dataset (PIDD), which is accessible online in the UCI Machine Learning Repository [4], consists of 786 instances, and a total of 9 of these attributes are used in this research. Different machine learning algorithms, such as Logistic Regression (LG), Support Vector Machines (SVM), Decision Tree (DT), Random Forest (RF), and K-Nearest Neighbor (KNN) classification algorithms, were performed against the Pima Indians Diabetes Dataset (PIDD). We examined all of the above algorithms and observed that each algorithm gives a result with different accuracies. Among all of the above algorithms, we picked out the ones which gave us the most accurate results. Decision Tree and Logistic Regression were therefore chosen, since they had the highest accuracy rates of 81% and 80%, respectively. The diabetic researcher is therefore curious to observe the most recent studies utilizing various machine learning approaches. Diabetes is one of the main priorities of medical research, which generates a lot of data due to the substantial social impact of this particular disease. Research is a crucial strategy that can be used to develop knowledge to efficiently utilize sizable amounts of diabetes-related data.
The current study contributes to the existing literature by conducting a comprehensive analysis of six classification algorithms for diabetes prediction, shedding light on their relative performance and identifying Logistic Regression as the most precise approach. This study employs a diverse set of performance metrics and multiple software tools, demonstrating methodological versatility. Furthermore, it outlines plans for the development of web-based and Android applications for diabetes prediction and management, emphasizing the practical implications of the research. The commitment to ongoing research and algorithm refinement adds to the literature by promoting continuous innovation in healthcare-related machine learning applications, ultimately enhancing our understanding of the potential of machine learning in addressing diabetes and other healthcare challenges.
2. Related Works
In the Diabetes Using Classification Algorithms (PDCA) research paper, Deepti Sisodia et al. (2018) compared only three algorithms, namely Decision Tree, Naïve Bayes, and Support Vector Machine (SVM) in experiments performed by using Pima Indians Diabetes Dataset (PIDD). By applying different classification algorithms, the best and highest accuracy is from Naïve Bayes of at 76.30% [5].
In the Predicting Diabetes Mellitus using Data Mining Techniques (PDMDMT) research paper by J. Steffi, Dr. R. Balasubramanian et al. (2018), the authors compared five algorithms, namely Artificial Neural Network (ANN), Naïve Bayes, Support Vector Machine (SVM), Logistic Regression, and C5.0 [6].
As proven by the Improved J48 Classification Algorithms for the Prediction of the Diabetes research paper, Gaganjot Kaur and Amit Chhabra et al. (July 2014) used the J48 Decision Tree algorithm to improve the accuracy of the J48 algorithm and the C4.5. These algorithms were used with an actual accuracy of 73.8281% and the accuracy of the proposed algorithm is 99.87% [7].
Madhusmita Rout, Amandeep Kaur et al. (2019) applied SVM, Naïve Bayes, Decision Tree, KNN, and Logistic Regression techniques to the proposed prediction model and made an accurate comparison of those algorithms. Experimental results show that the Logistic algorithm had an accuracy of 82.35%, which has proven to be better than the other applied algorithms [8].
Varma, K. M., and Panda, B. S. et al. (2019) showed how the data mining classification algorithms C5.0, Logistic Regression, Naïve Bayes, Support Vector Machine, and Artificial Neural Networks are utilized to demonstrate genuine diabetes mellitus predictions. Thereafter, a near investigation is made between them, utilizing metric system. As a result of the research work, C5.0 and Logistic Regression were equally good based on their accuracy measurements of 74.63% and 74.67%, respectively [9].
Wu, H., Yang, S., Huang, Z., He, J., and Wang, X. et al. (2018) used the PIDD dataset with the K-Means and Logistic Regression algorithms to perform the task, which has the best accuracy of 95.42% [10].
O. Dr. O., S. Dr. K., and B. Ramudu et al. (2020) “Used machine learning Techniques for diabetes prediction”. The study utilized several regression algorithms, including SVM, KNN, and Artificial Neural Networks (ANN), to analyze the PIMA diabetes dataset. The research was conducted using R-Studio software 4.0.2 version, and Logistic Regression was found to have the highest accuracy at 78% [11].
Das H., Naik, B., and Behera, H. et al. (2018) investigated diabetes forecasts utilizing different order calculations, for example, J48 and Bayesian naivety, to analyze the infection rapidly. The proposed model aids patients and clinicians in saving time by creating reports rapidly from an information store. It was assessed utilizing WEKA and MATLAB programming. Further investigation can be conducted with a mixture of information-digging procedures for accurate and precise outcomes [12].
Abdulhadi, N., and Al-mousa, A. et al. (2021) used different machine learning algorithms like Logistic Regression Classifier, Linear Discriminant Analysis (LDA), Linear Support Vector Machine, SVC (Support Vector Classifier) with Polynomial Kernel, Random Forest Classifier, and Voting Classifier to evaluate the different accuracies. The best ML algorithm among them is the Random Forest classifier, which achieves 82% accuracy on the PIMA diabetes dataset [13].
Based on the study by Chou, C.-Y., Hsu, D.-Y., Chou, C.-H. et al. (2023) diabetes prediction was performed and evaluated by applying various machine learning algorithms, including Logistic Regression, Binary Neural Network, Decision Forest, and Decision Tree to evaluate model performance, accuracy, precision, recall, and the F-measure. The two-level augmented Decision Tree was the most efficient model, outperforming all other models on the PIMA diabetes dataset with an augmented patient ID under curve result of 0.991 [14]. A comparison of our proposed study with previous literature studies is mentioned and illustrated in Table 1 below.
Table 1.
Comparison to past literature.
3. Model and Classification Algorithms
We encourage research data to be archived in data repositories wherever possible.
3.1. Dataset Description
We utilized the PIMA diabetes dataset from the UCI Machine Learning Repository for this study [4]. The 768 illustrations, 8 characteristics, and 1 class attribute that carries the values tested positive (1) and tested negative (0) make up this dataset [5]. Two toolboxes, specifically the WEKA (Waikato Environment for Knowledge Analysis) device developed by the University of Waikato, New Zealand, which contains apparatuses for data pre-processing, characterization, and relapse [20,21], are used in this paper to perform and really examine the exactness and execution of various order calculations. Table 2 depicts the datasets, attributes, minimum, maximum, mean, and standard deviation (SD).
Table 2.
Attribute descriptions.
3.1.1. Simple Size
The dataset consists of 768 observations (rows), making it a moderate dataset for a machine learning study.
3.1.2. Features
There are eight attributes (columns) in the dataset, including:
- Number of pregnancies;
- Plasma glucose concentration;
- Diastolic blood pressure;
- Triceps skinfold thickness;
- 2 h serum insulin;
- Body mass index (BMI);
- Diabetes pedigree function;
- Age.
3.1.3. Target Variable
The binary variable being targeted indicates whether diabetes is detected or not. Generally, a value of 1 indicates the presence of diabetes, while a value of 0 indicates its absence.
3.1.4. Sex Distribution
There is no significant gender distribution in the dataset. It mainly focuses on diabetes status and health-related features. Therefore, the dataset itself does not contain information on gender distribution.
3.1.5. Diabetes Prevalence
The dataset contains details of the diabetes status of 768 sample members, including whether they have diabetes or not. By multiplying the number of people with diabetes (target variable = 1) and dividing it by the total number of observations (768), it is possible to estimate the prevalence of diabetes in the dataset.
3.1.6. Missing Values
Datasets may contain missing values, which can affect data analysis and modeling. Data preprocessing steps may be required to handle missing data.
3.2. Detailed Accuracy
Generally, we know that the prediction process consists of our main attributes, which are called true positive (TP), true negative (TN), false positive (FP), and false negative (FN) [6] and are used to calculate the precision, recall, MCC, F-measure score, true positive rate (TPR), true negative rate (TNR), false positive rate (FPR), false negative rate (FNR), and accuracy.
3.2.1. Precision
A classification model’s precision is a metric that assesses its capacity to correctly identify only the pertinent data points [22]. Mathematically, precision can be computed using the formula below:
By using Equation (1), we can calculate the precision value [22].
3.2.2. Recall
The recall is a metric that evaluates the ability of a model to identify all the relevant cases within a dataset [14]. Mathematically, recall can be computed using the formula below:
By using Equation (2), we can calculate the recall value [14].
3.2.3. Mathews Correlation Coefficient
The Mathews correlation coefficient (MCC) is more robust statistical measure than others, as it produces a higher score when the model achieves good outcomes across all four classes of the confusion matrix (true positive, false negative, true negative, and false positive) relative to the size of the positive and negative components in the dataset [22]. Mathematically, the MCC can be calculated by using the formula below:
By using Equation (3), we can calculate the MCC value [22].
3.2.4. True Positive Rate
A true positive is an outcome where the model correctly predicts the positive value. Mathematically, the true positive can be calculated by the formula below:
By using Equation (4), we can calculate the TPR value.
3.2.5. True Negative Rate
In a classification problem, a true negative refers to an outcome where the model correctly predicts the negative class. Mathematically, the true negative can be calculated by using the formula below:
By using Equation (5), we can calculate the TNR value.
3.2.6. False Positive Rate
In a classification problem, a false positive is an outcome where the model incorrectly predicts the positive class. Mathematically, the false positive rate can be calculated by using the formula below:
By using Equation (6), we can calculate the FPR value.
3.2.7. False Negative Rate
A false negative occurs when the model predicts a negative class. False negatives are a type of error in which the model fails to detect a true positive instance. Mathematically, the false negative can be calculated by using the formula below:
By using Equation (7), we can calculate the FNR value.
3.2.8. Mean Absolute Error
The formula calculates the sum of the absolute differences between each predicted value and its corresponding true value and then divides by the total number of predictions to obtain the average error. The lower the MAE value, the better the predictive model is performing. Mathematically, the MAE can be calculated by using the formula below:
By using Equation (8), we can calculate the MAE value.
3.2.9. Root Mean Squared Error
RMSE is the standard deviation of errors that occur when predicted on a dataset. This is similar to MSE (Main Squared Error), but the root of the value is considered when determining the accuracy of the model. Mathematically, the RMSE can be calculated by using the formula below [23]:
By using Equation (9), we can calculate the RMSE value [23].
3.2.10. Relative Absolute Error
Relative Absolute error is expressed as a ratio, and a minor error is compared to the errors produced by a small model. Mathematically, the RAE can be calculated by using the formula below:
By using Equation (10), we can calculate the RAE value.
3.2.11. Root Relative Absolute Error
RRAE (Relative Ratio Absolute Error) is a metric that can be used to evaluate the performance of a predictive model. It is calculated by dividing the Mean Absolute Error (MAE) of the model by the error of the Zero-R classifier, which is a simple classifier that always predicts the most frequent class in the training data. The formula for RRAE is
By using Equation (11), we can calculate the RRAE value.
4. Methods and Results
This experiment uses two sets of programming tools in WEKA (Waikato Environment for Knowledge Analysis), a combination of machine learning algorithms utilizing Python libraries such as MATLAB, Jupiter Notebook, and Scikit Learn Library. The result is generated from both programming tools which compares their results and graphs and calculates accuracy, error rate, F-measure, PRC (precision–recall curves area), MCC (Matthew’s correlation coefficient), and ROC (receiver operating characteristic) areas. These experiments are performed using classification algorithms, for instance, Random Forest, Logistic Regression, K-Nearest Neighbors, Decision Tree, Naïve Bayes, and Support Vector Machine. The results and evolutions that we have performed and concluded, using both WEKA and Python, have been uploaded to GitHub, which is publicly accessible at https://github.com/wisalsafi/Diabetes-Prediction-Using-Machine-Learning-Algorithms-with-PIMA-Diabetes-Dataset/tree/main/ML%20Algoritms%20for%20Diabetes accessed on 7 July 2023.
The dataset used in the proposed work is the PIMA diabetes dataset, which consists of 768 instances. We performed our experiments and split the dataset by using a percentage split. “Percentage split” in machine learning often refers to dividing a dataset into separate subsets for training, validation, and testing. To assess the effectiveness of machine learning models and make sure they generalize successfully to new, unexplored data, segmentation is a crucial step. It is essential to choose a distribution that suits your particular situation, the size of your dataset, and the availability of the data. When the dataset is small, you can also use methods like cross-validation to obtain the most out of your data.
4.1. Decision Tree
The Decision Tree algorithm is utilized in this paper on the grounds that the Decision Tree calculation has the best precision proportion in the PIMA dataset and enjoys a few benefits, for example, it is not difficult to peruse and decipher, it is simple to get ready, and it requires less information cleaning. Decision Trees are regulated AI calculations that are utilized for both grouping and relapse strategies. Managed implies it requires a name for its execution. A Decision Tree is a supporting apparatus with a tree-like design that models potential results and assets. Decision Trees furnish a method for giving calculations contingent control articulations. They incorporate branches that address the dynamic advances that can prompt the endorsement of results [24]. The Decision Tree gives a solid strategy to arrangements and expectations in the analysis of diabetes. There are different types of Decision Trees available for classifying data, such as ID3, C4.5, C5.0, CART, Decision Stump, J48, and Heoffding Tree [19].
4.1.1. Mathematical Equations
Decision Trees have three main mathematical formulas, including information gain, entropy, and gain.
Information Gain
Information gain is a measure that determines the change in entropy when a dataset is partitioned based on an attribute. It indicates the amount of new information that the attribute provides about the target variable. The Decision Tree construction process relies on information gain values to determine the sequence in which nodes should be split. The algorithm aims to maximize the information gain at each step, selecting the attribute that offers the greatest information gain as the first to be split. The value can be computed using the formula below:
From Equation (12), we can calculate information gain.
Entropy
Entropy is a metric to compute impurities in certain attributes. It determines randomness in the data. Entropy can be calculated as follows:
From Equation (13), we can calculate Entropy.
Gain
The gain is a measure of impurity or purity used when constructing a Decision Tree in the CART algorithm. Gain can be calculated using the formula below:
From Equation (14), we can calculate Gain.
4.1.2. Confusion Matrix
A confusion matrix is a table that summarizes the results of a classification model on a set of input data. It presents the count of correct and incorrect predictions for each class [5]. The matrix includes four categories:
- True Positive (TP): It is positive for both observed and predicted.
- False Positive (FP): It is negative for both observed and predicted.
- False Negative (FN): It is positive for observed, but negative for predicted.
- True Negative (TN): It is positive for predicted, but negative for observed.
To calculate the accuracy score, the correct values are placed along a diagonal line from the top left to the bottom right of the matrix. Adding the values on this diagonal line (134 + 48 = 182) gives the accuracy of the model, which, in this case, is 79.13%.
4.1.3. Result through WEKA
Table 3 shows the confusion matrix by WEKA by applying the decision tree classification algorithm.
Table 3.
Confusion matrix through WEKA using the decision tree algorithm.
Table 4.
Actual class and ICI details achieved via Decision Tree through WEKA.
Table 5.
Decision Tree details of accuracy through WEKA.
India’s PIMA diabetes dataset uses 760 instances, but here we experimented on the WEKA tool by using a percentage split and then taking a percentage share of 70%, which holds only 230 instances, and performing experiments that give us the best accuracy ratio, like the FPR (false positive ratio), TPR (true positive ratio), Prec (precision), F-M (F-measure), and Rec (recall).
4.1.4. Result through Python
Table 6 shows the confusion matrix by Python by applying the decision tree classification algorithm.
Table 6.
Confusion matrix through Python using decision tree algorithm.
Table 7 shows actual class, ICI, and accuracy details, whereas Table 8 shows the confusion matrix [25].
Table 7.
Actual class and ICI details achieved via Decision Tree through Python.
Table 8.
Decision Tree details of accuracy through Python.
4.2. Logistic Regression
Logistic Regression is a supervised machine learning algorithm that models the likelihood of discrete outcomes when input variables are given. This helps in understanding the alliance between multiple independent variables and one dependent variable [8]. It is an algorithm that takes two values, Yes or No, 0 or 1, and True or False [9]. Logistic Regression is a transformation of linear regression using the sigmoid function. Logistic Regression solves many problems encountered in fermium product development for which linear regression cannot be performed because, instead of predicting a numerical value (for example, a user’s total lifetime income), it predicts a discrete and dichotomous value (e.g., the user will spend or not spend money for the product). For this reason, Logistic Regression might more accurately be termed logistic classification [26].
4.2.1. Linear Regression
- y is the dependent variable.
- β0, β1, β2, …, βn are the regression coefficients for the intercept.
- X1, X2, X3, … and Xn are the independent variables [26].
4.2.2. Sigmoid Function
Apply the sigmoid function on linear regression and the equation will be
where
- p is the predicted probability of the dependent variable being 1 [26].
4.2.3. Result through WEKA
Table 9 shows the confusion matrix by WEKA by applying the logistic regression algorithm.
Table 9.
Confusion matrix through WEKA using logistic regression algorithm.
Table 10.
Actual class and ICI details achieved via Logistic Regression through WEKA.
4.2.4. Result through Python
Table 11 shows the confusion matrix by Python by applying the logistic regression algorithm.
Table 11.
Confusion matrix through Python using logistic regression algorithm.
Table 12 shows actual class, ICI, and accuracy details [25].
Table 12.
Actual class and ICI details achieved via Logistic Regression through Python.
4.3. Random Forest
Random Forest is a machine learning algorithm that has evolved from a Decision Tree [27]. Random Forest is used in classification models. It works in the following way: to classify an attribute, every Decision Tree algorithm comes up with a classification on the input data given, and afterward, Random Forest collects and predicts the most casted ballot expectation. Basically, the input from each tree is sample data from the dataset. In basic words, Random Forest uses many models of Decision Trees to achieve a better prediction model.
4.3.1. Mathematical Equations
- FRF (x) is the prediction of Random Forest for input x.
- Ft (x) is the prediction of t-th Decision Tree for input x.
- T is the total number of Decision Trees in the Random Forest [27].
4.3.2. Result through WEKA
Table 13 shows the confusion matrix by WEKA by applying the random forest algorithm.
Table 13.
Confusion matrix through WEKA using random forest algorithm.
Table 14 shows the details accuracy by utilizing WEKA [25].
Table 14.
Random Forest details of accuracy through WEKA.
4.3.3. Result through Python
Table 15 shows the confusion matrix by Python by applying the random forest algorithm.
Table 15.
Confusion matrix through Python using random forest algorithm.
Table 16 shows the details accuracy by utilizing Python [25].
Table 16.
Random Forest details of accuracy through Python.
4.4. K-Nearest Neighbors
KNN is a classification-focused supervised machine learning algorithm [11]. K stands for the quantity of nearest neighbors in KNN. The K value affects how well this algorithm performs. This is a non-parametric algorithm, and learning is slow because it does not pick up during the training stage, is very simple to implement, and is applied on a large dataset [8]. KNN performs three fundamental stages: distance estimation, looking for adjacent neighbors, and deciding in favor of marks [15].
4.4.1. Mathematical Equation
4.4.2. Result through WEKA
Table 17 shows the confusion matrix by WEKA by applying the K-NN algorithm.
Table 17.
Confusion matrix through WEKA. using K-NN algorithm.
Table 18 shows actual class, ICI, and accuracy details, and Table 19 shows the confusion matrix [25].
Table 18.
Actual class and ICI details achieved via KNN through WEKA.
Table 19.
KNN details of accuracy through WEKA.
4.4.3. Result through Python
Table 20 shows the confusion matrix by Python by applying the K-NN algorithm [28].
Table 20.
Confusion matrix through Python.
Following Table 21 shows actual class, ICI, and accuracy details, and Table 22 shows the confusion matrix [25].
Table 21.
Actual class and ICI details achieved via KNN through Python.
Table 22.
KNN details of accuracy through Python.
4.5. Naïve Bayes
The Naïve Bayes algorithm is a supervised machine learning algorithm. Naïve Bayes is based on the Bayesian theorem, which shows the probability of a hypothesis when the proof is provided. This algorithm also states that each feature of a particular dataset makes an equal and independent contribution to the problematic target class [5]. The Naïve Bayes algorithm shows good performance on huge datasets having high dimensionality [11].
4.5.1. Mathematical Equation
- P(H): The probability that hypothesis H is correct. P(S): Probability of S data. Previous probability of H [11].
- P(H|S): Probability of hypothesis H given data D.
- P(S|H): The probability that the S data is given the hypothesis H.
4.5.2. Result through WEKA
Table 23 shows the confusion matrix by WEKA by applying the Naïve Bayes algorithm.
Table 23.
Confusion matrix through WEKA using Naïve Bayes Algorithm.
Table 24 shows actual class, ICI, and accuracy details, and Table 25 shows the confusion matrix [25].
Table 24.
Actual class and ICI details achieved via Naïve Bayes through WEKA.
Table 25.
Naïve Bayes details of accuracy through WEKA.
4.5.3. Result through Python
Table 26 shows the confusion matrix by Python by applying the Naïve Bayes algorithm.
Table 26.
Confusion matrix through Python using Naïve Bayes algorithm.
Table 27 shows actual class, ICI, and accuracy details, and Table 28 shows the confusion matrix [25].
Table 27.
Actual class and ICI details achieved via Naïve Bayes through Python.
Table 28.
Naïve Bayes details of accuracy through Python.
4.6. Support Vector Machines
SVM is a supervised machine learning algorithm, which is used for both classification and regression problem types. It can easily perform multiple categorical and continuous variables [29]. SVM plays out the classification task by developing a hyperplane in a multi-faceted space that isolates instances of various class marks [30]. The hyperplane is a decision point that separates a set of objects that have different class labels. SVM has many applications, such as email classification, face detection, instruction detection, and gene classification.
4.6.1. Mathematical Equation
- t is the number of prepared models.
- , i = 1, …, t, are non-negative numbers.
- Derivatives of L P with respect to αi are zero.
- are the Lagrangian multipliers.
- is called Lagrangian.
The vector w and the constant b define the hyperplane [31].
4.6.2. Result through WEKA
Table 29 shows the confusion matrix by WEKA by applying the Support Vector Machine algorithm.
Table 29.
Confusion matrix through WEKA.
Table 30 shows actual class, ICI, and accuracy details, and Table 31 shows the confusion matrix [25].
Table 30.
Actual class and ICI details achieved via SVM through WEKA.
Table 31.
SVM details of accuracy through WEKA.
4.6.3. Result through Python
Table 32 shows the confusion matrix by Pyton by applying the Support Vector Machine algorithm.
Table 32.
Confusion matrix through Python using Support Vector Machine algorithm.
Table 33 shows actual class, ICI, and accuracy details, and Table 34 shows the confusion matrix [25].
Table 33.
Actual class and ICI details achieved via SVM through Python.
Table 34.
SVM details of accuracy through Python.
4.7. Accuracy and Inconsistence Rate
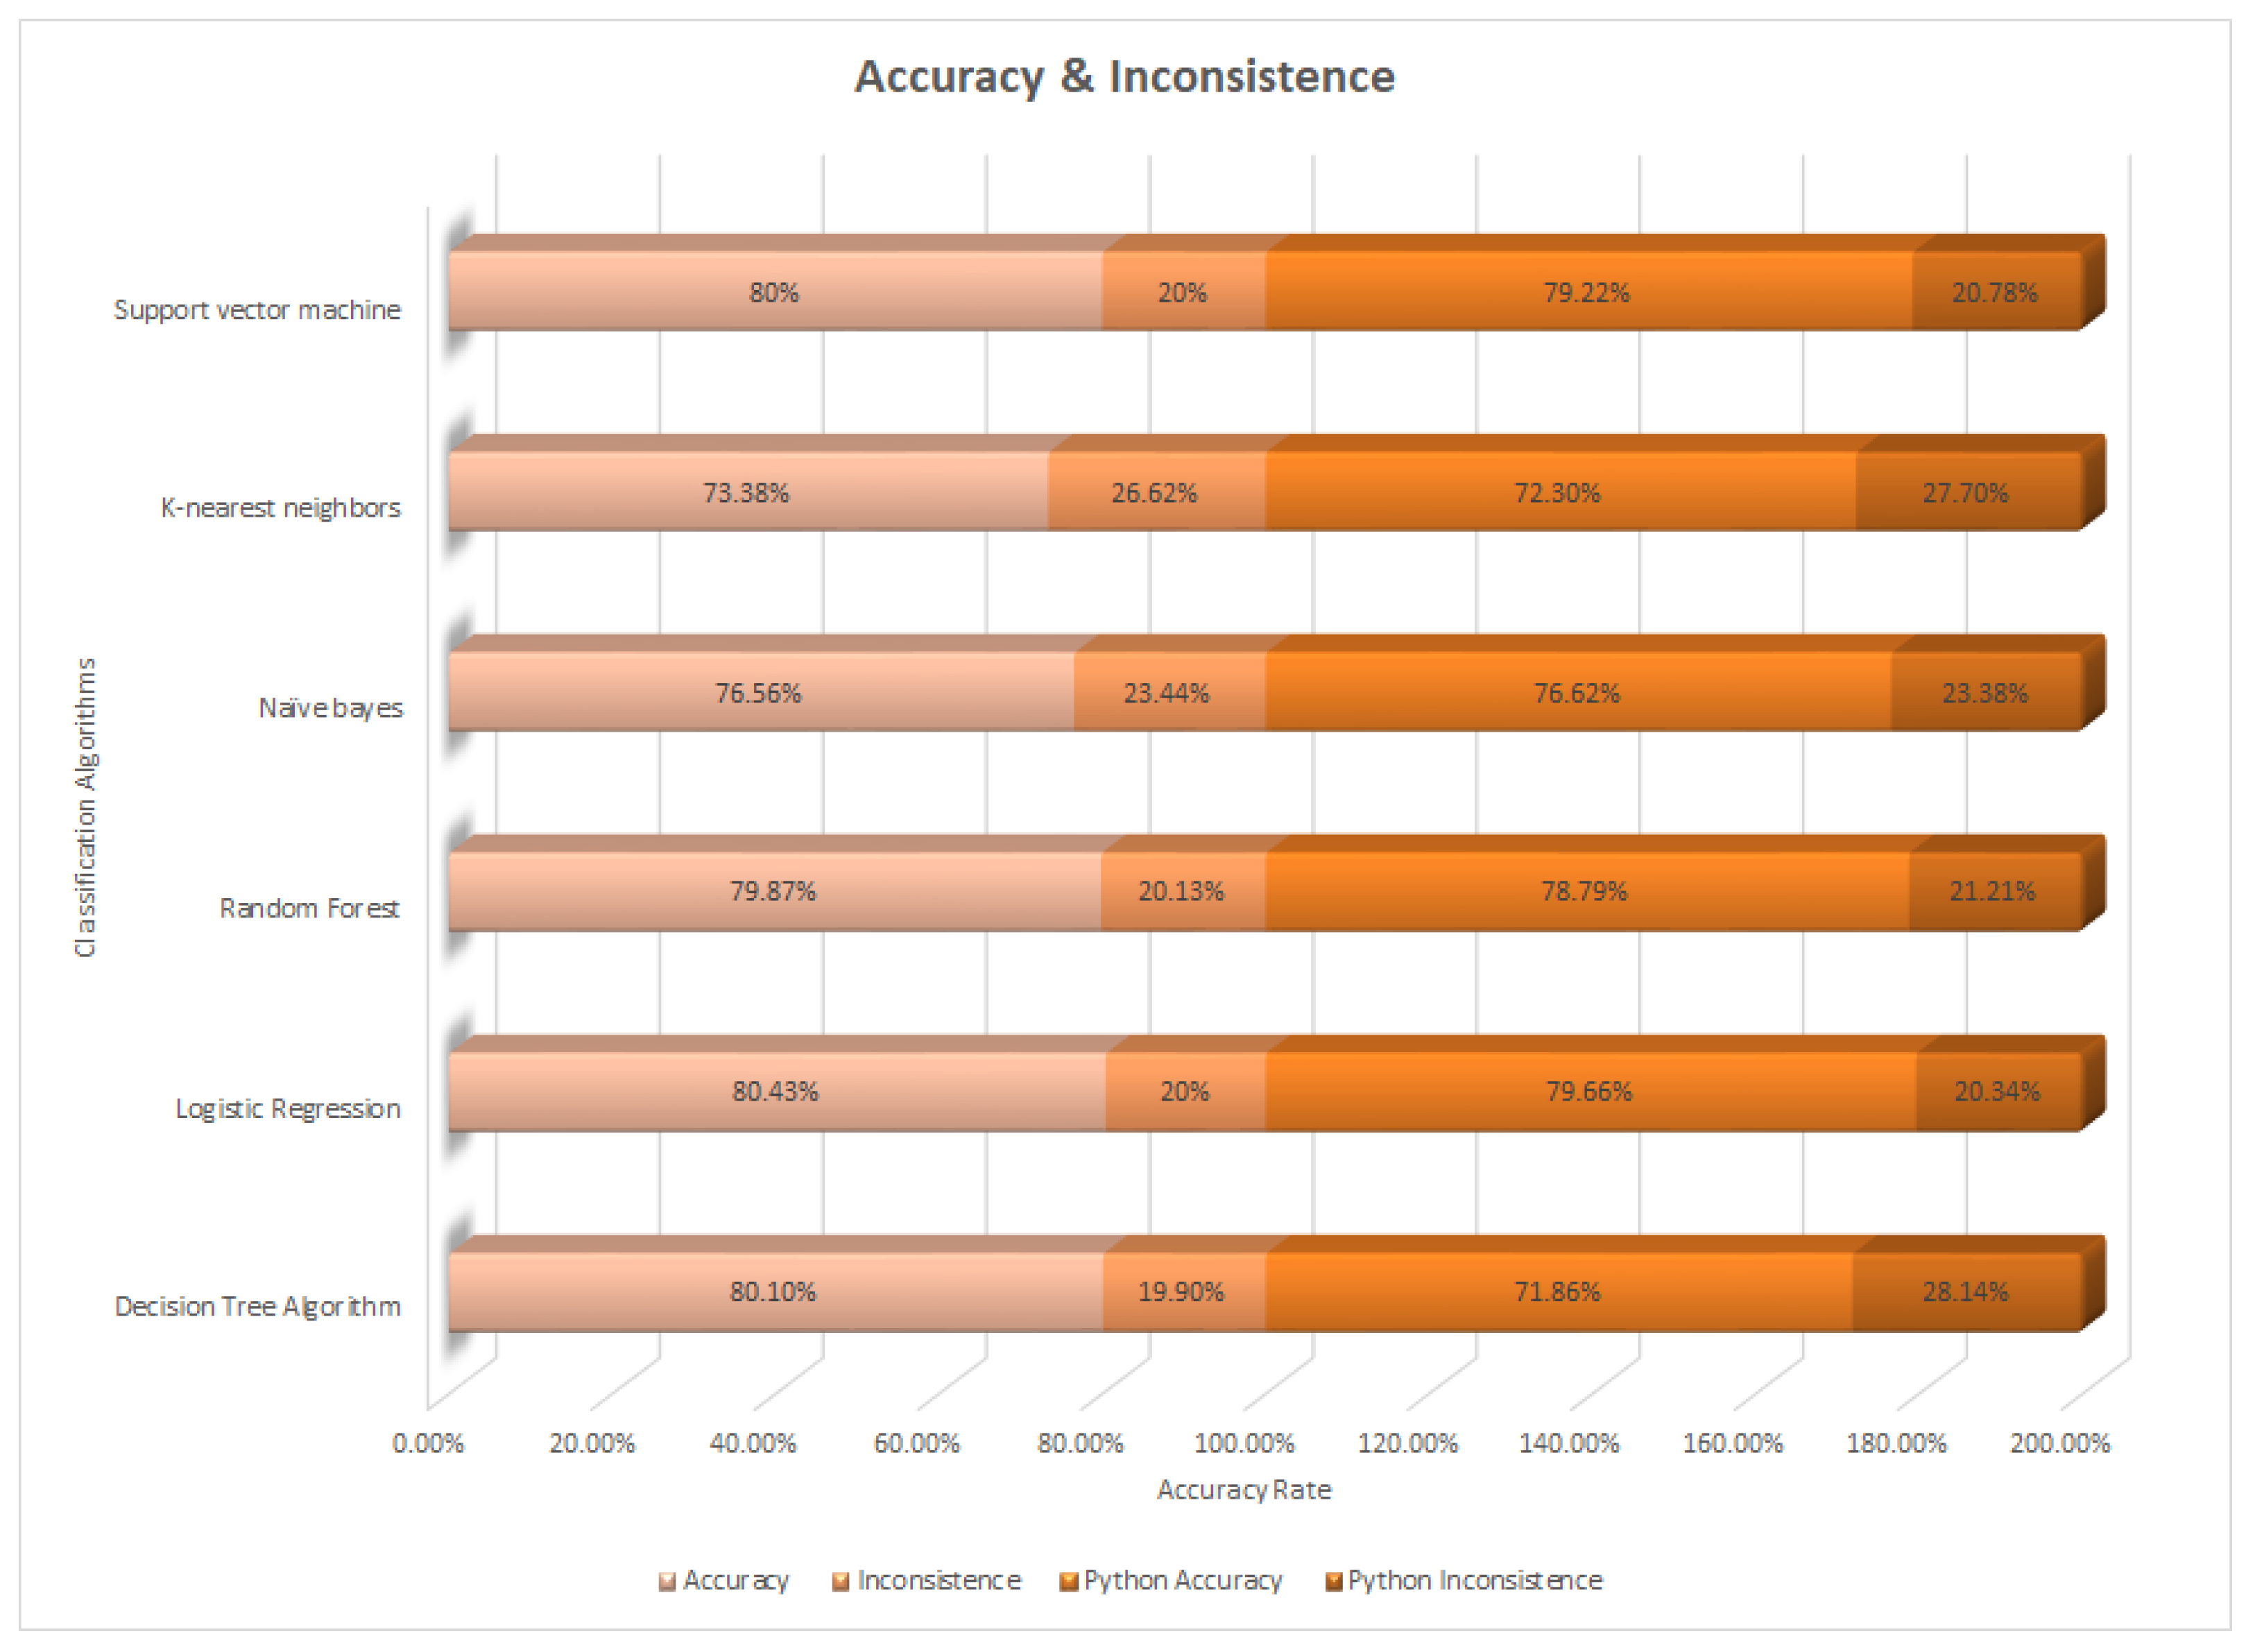
Table 35, below, shows the accuracy (actual class) and inconsistence (incorrectly classified instances) by using the WEKA tool and the Python library. We used six classification algorithms with different accuracy rates and selected the algorithm on the basis of the highest accuracy rate. We performed the experiment on different classification algorithms, and the result is shown in Table 31, as well as in Figure 1. We conclude that the highest and best accuracy was obtained by Logistic Regression at 80.43%, and the second highest accuracy was obtained by Decision Tree and Support Vector Machine, with 79.13% accuracy. The third one was Naïve Bayes, with an accuracy of 76.96% obtained through WEKA. By using the Python library, we obtained an accuracy better than WEKA, which has the highest accuracy of 81% obtained by Logistic Regression.
Table 35.
Accuracy and inconsistence rate.
Figure 1.
Accuracy and inconsistence rate.
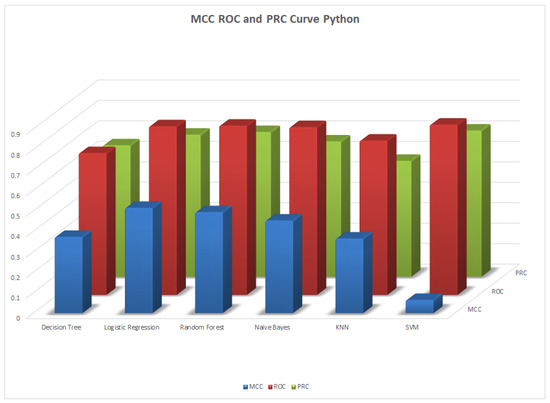
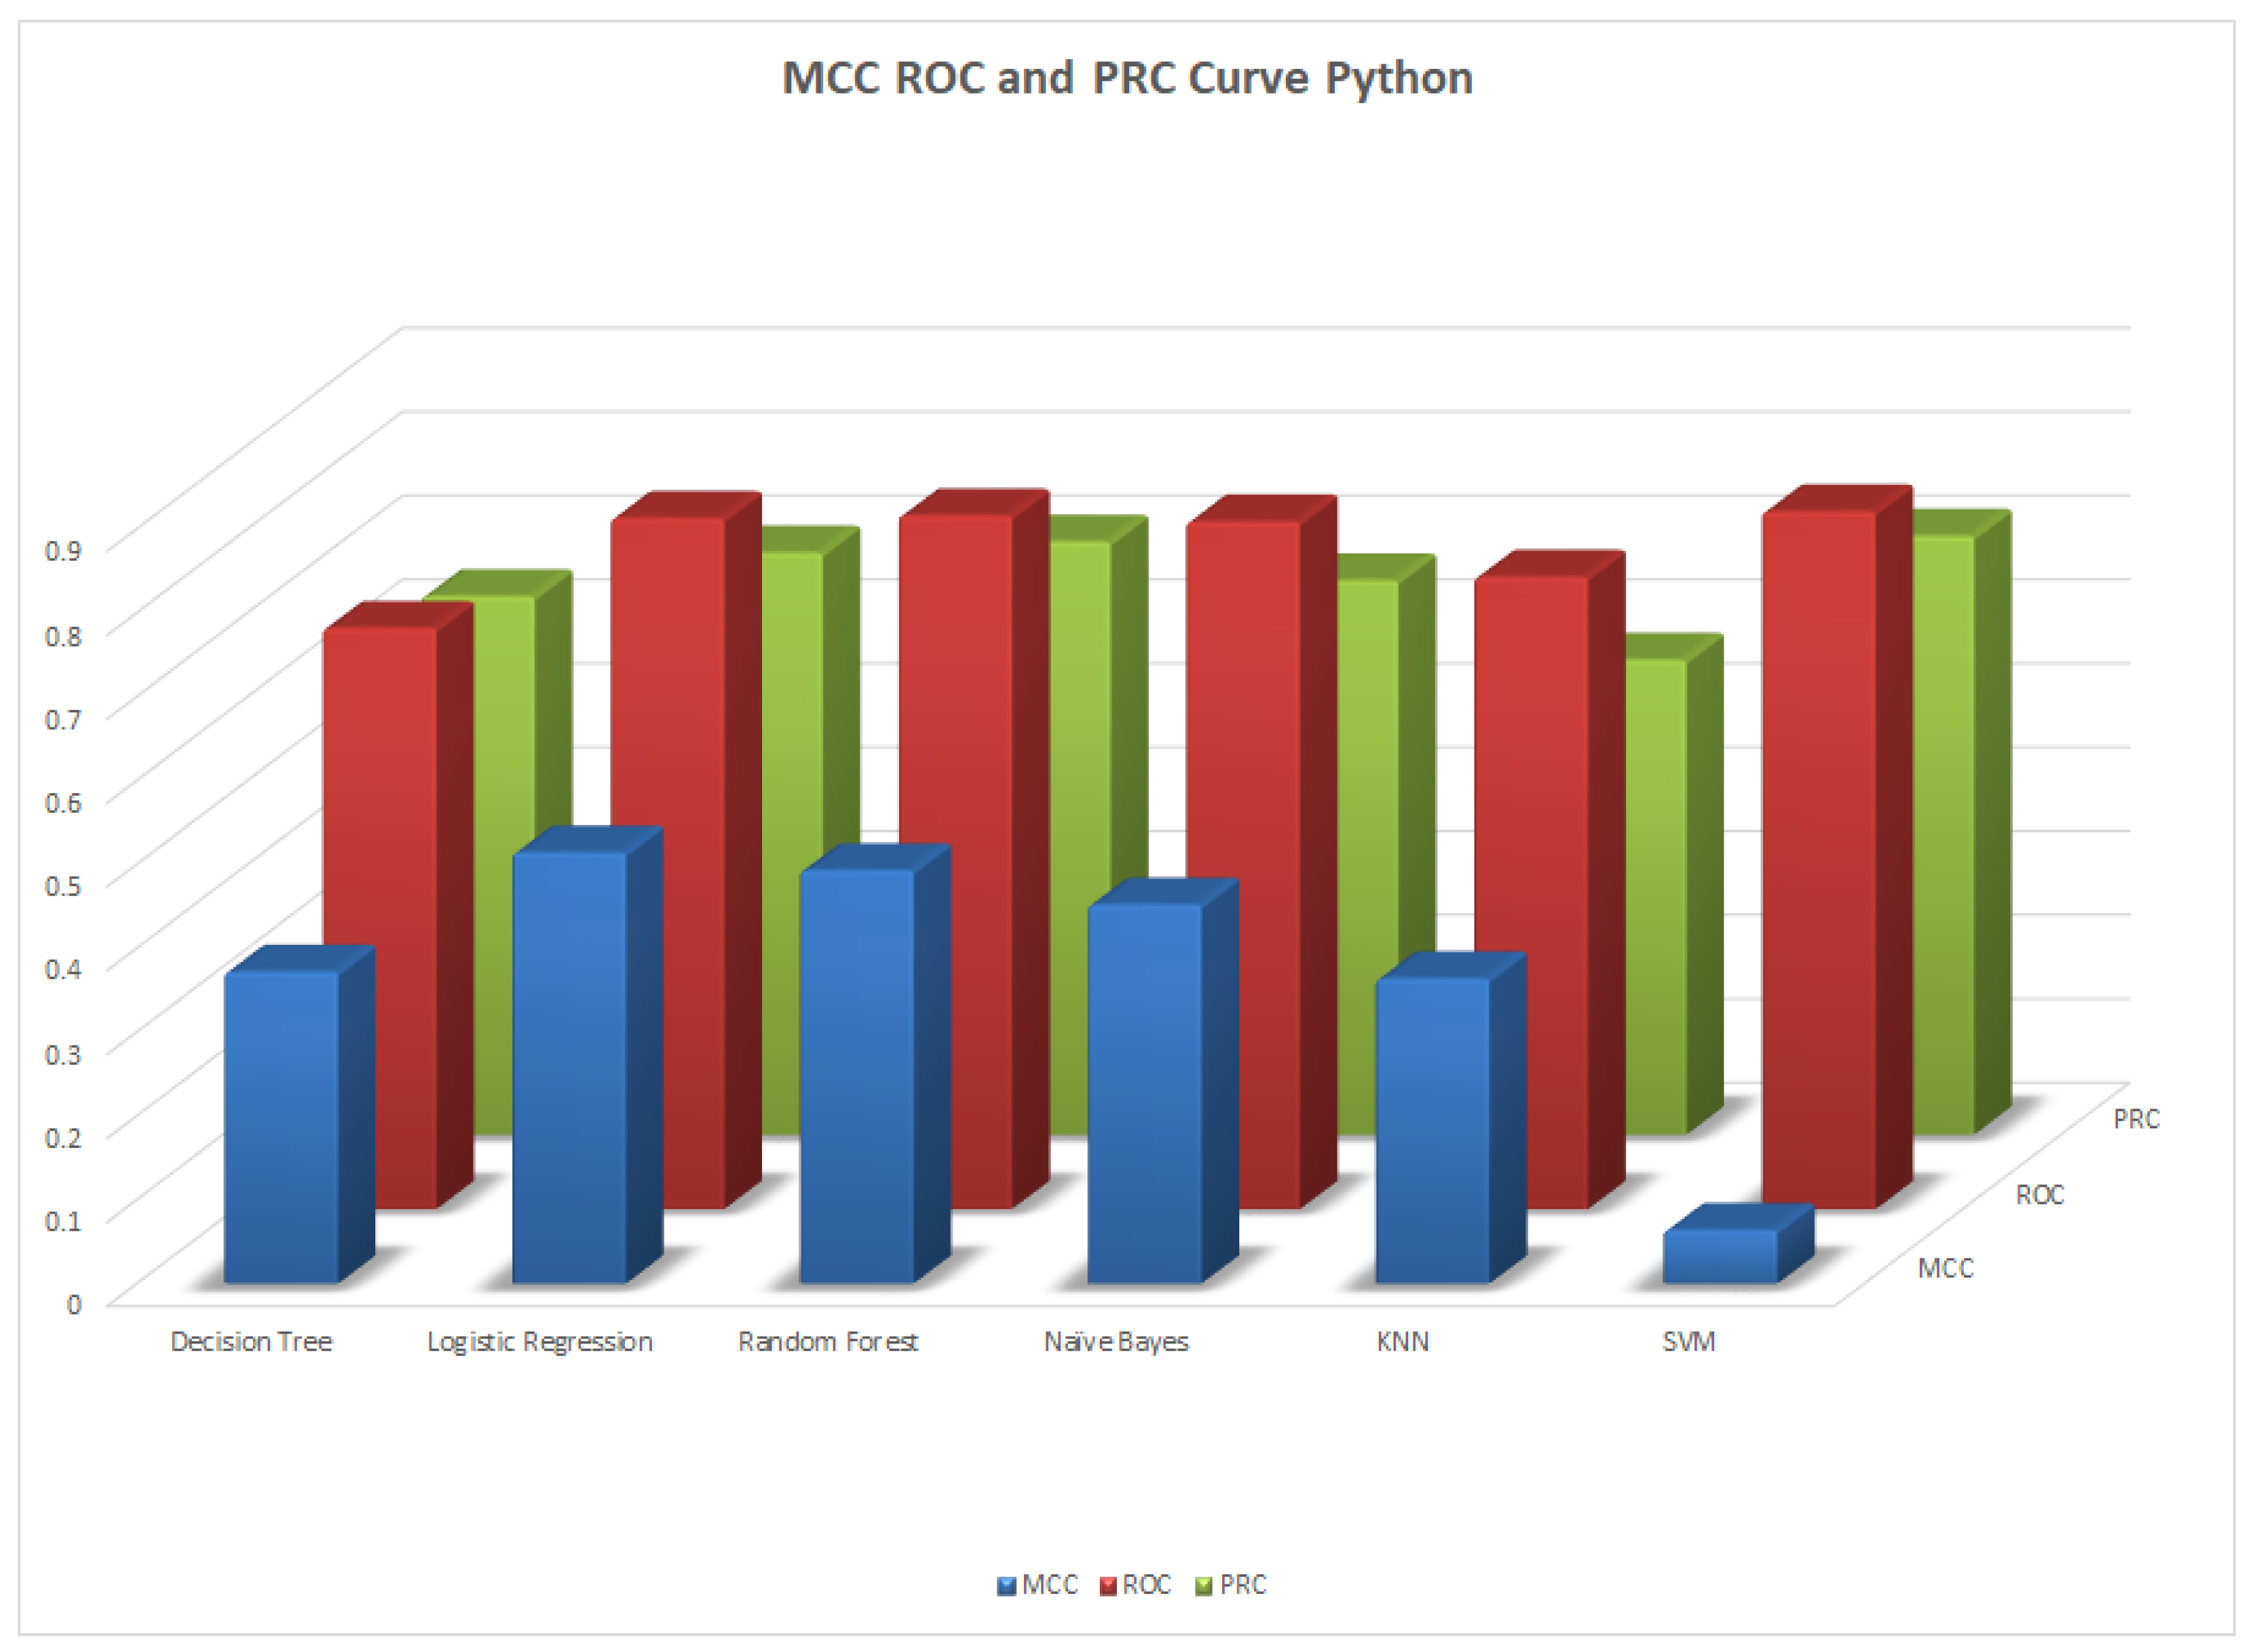
4.8. MCC, ROC, and PRC Area
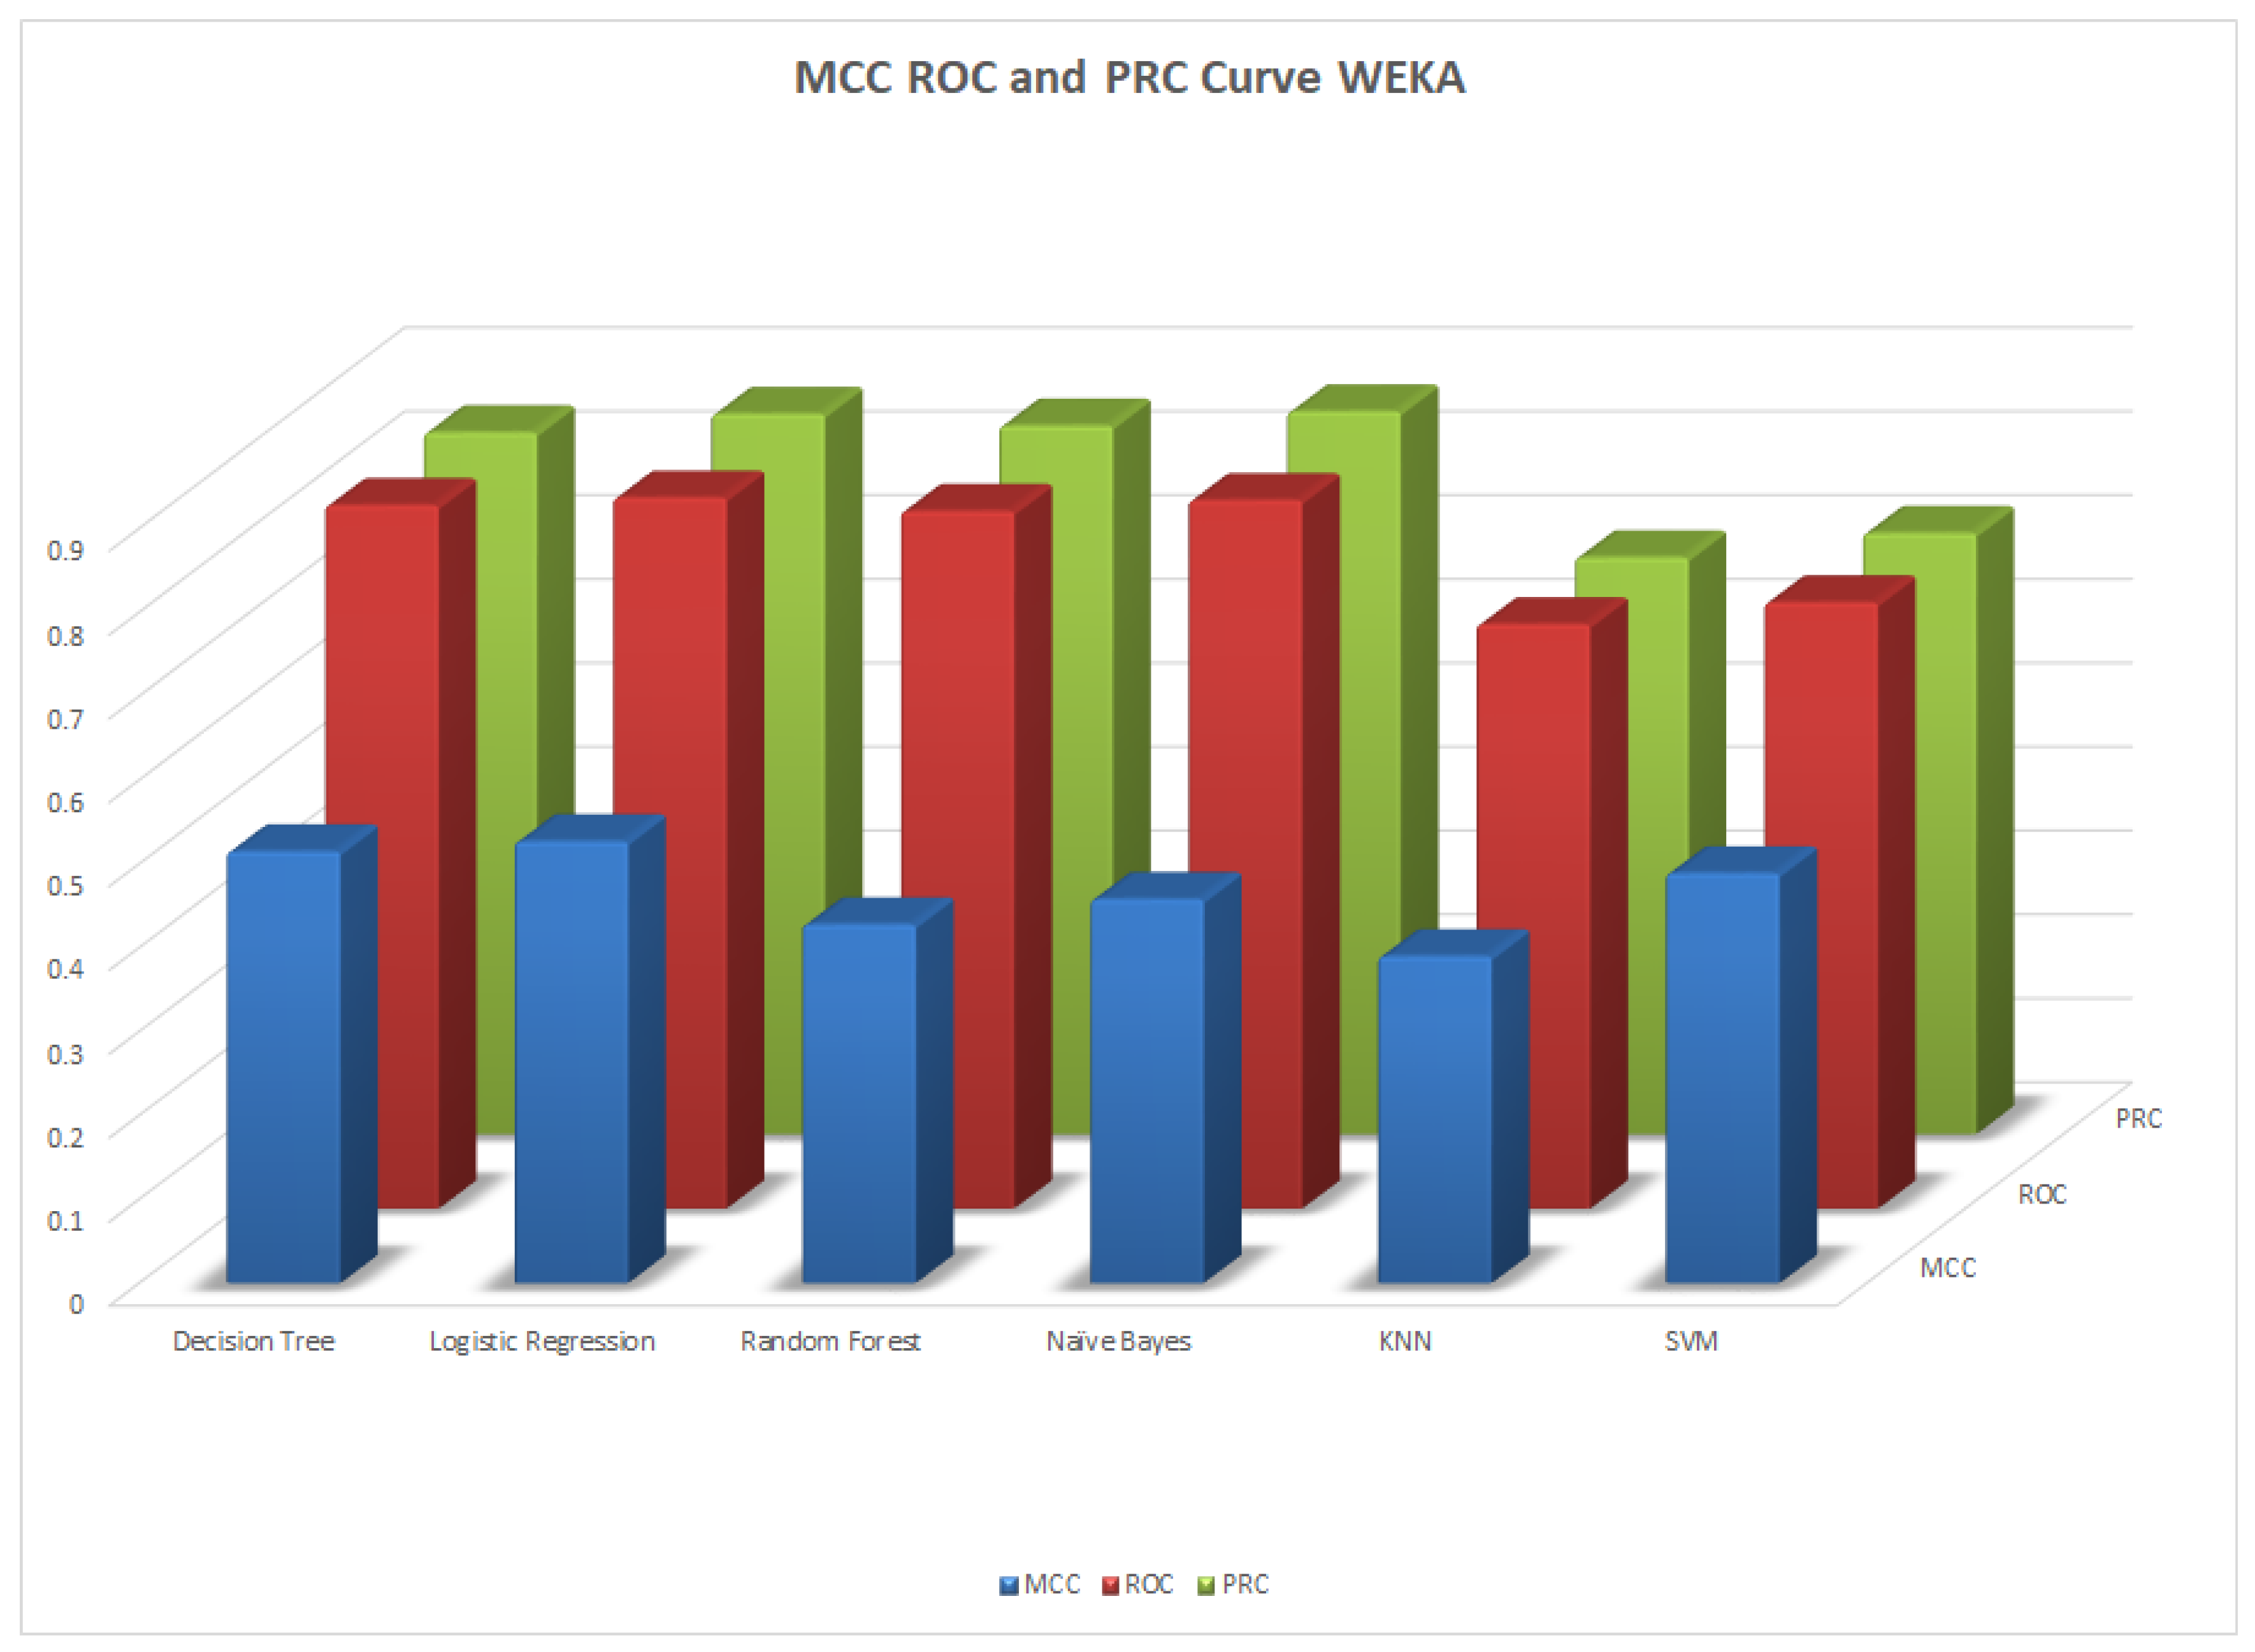
We illustrate the values and graph of the MCC (Matthews correlation coefficient), which is between +1 and −1; the MCC perfect score is +1 and the worst score is −1 [32]. The ROC (receiver operating characteristics) graphical plot shows the diagnostic values between 0 and 1 [33]. PRC (precision–recall curve) should be used when there is a moderate to large class imbalance; all of these have different values between 0 and 1 [34]. A comparison between WEKA and Python results is shown in Table 36 along with Figure 2 and Figure 3.
Table 36.
MCC, ROC, and PRA area.
Figure 2.
MCC, ROC, and PRC by WEKA.
Figure 3.
MCC, ROC, and PRC by Python.
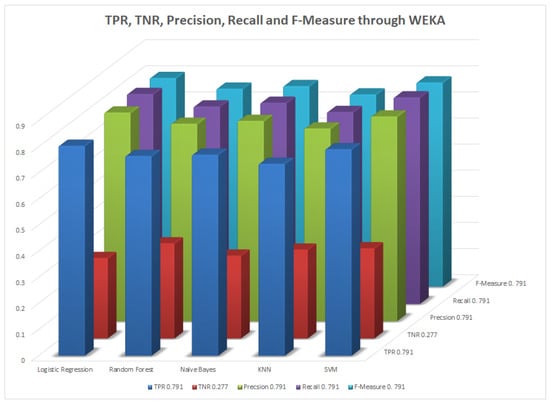
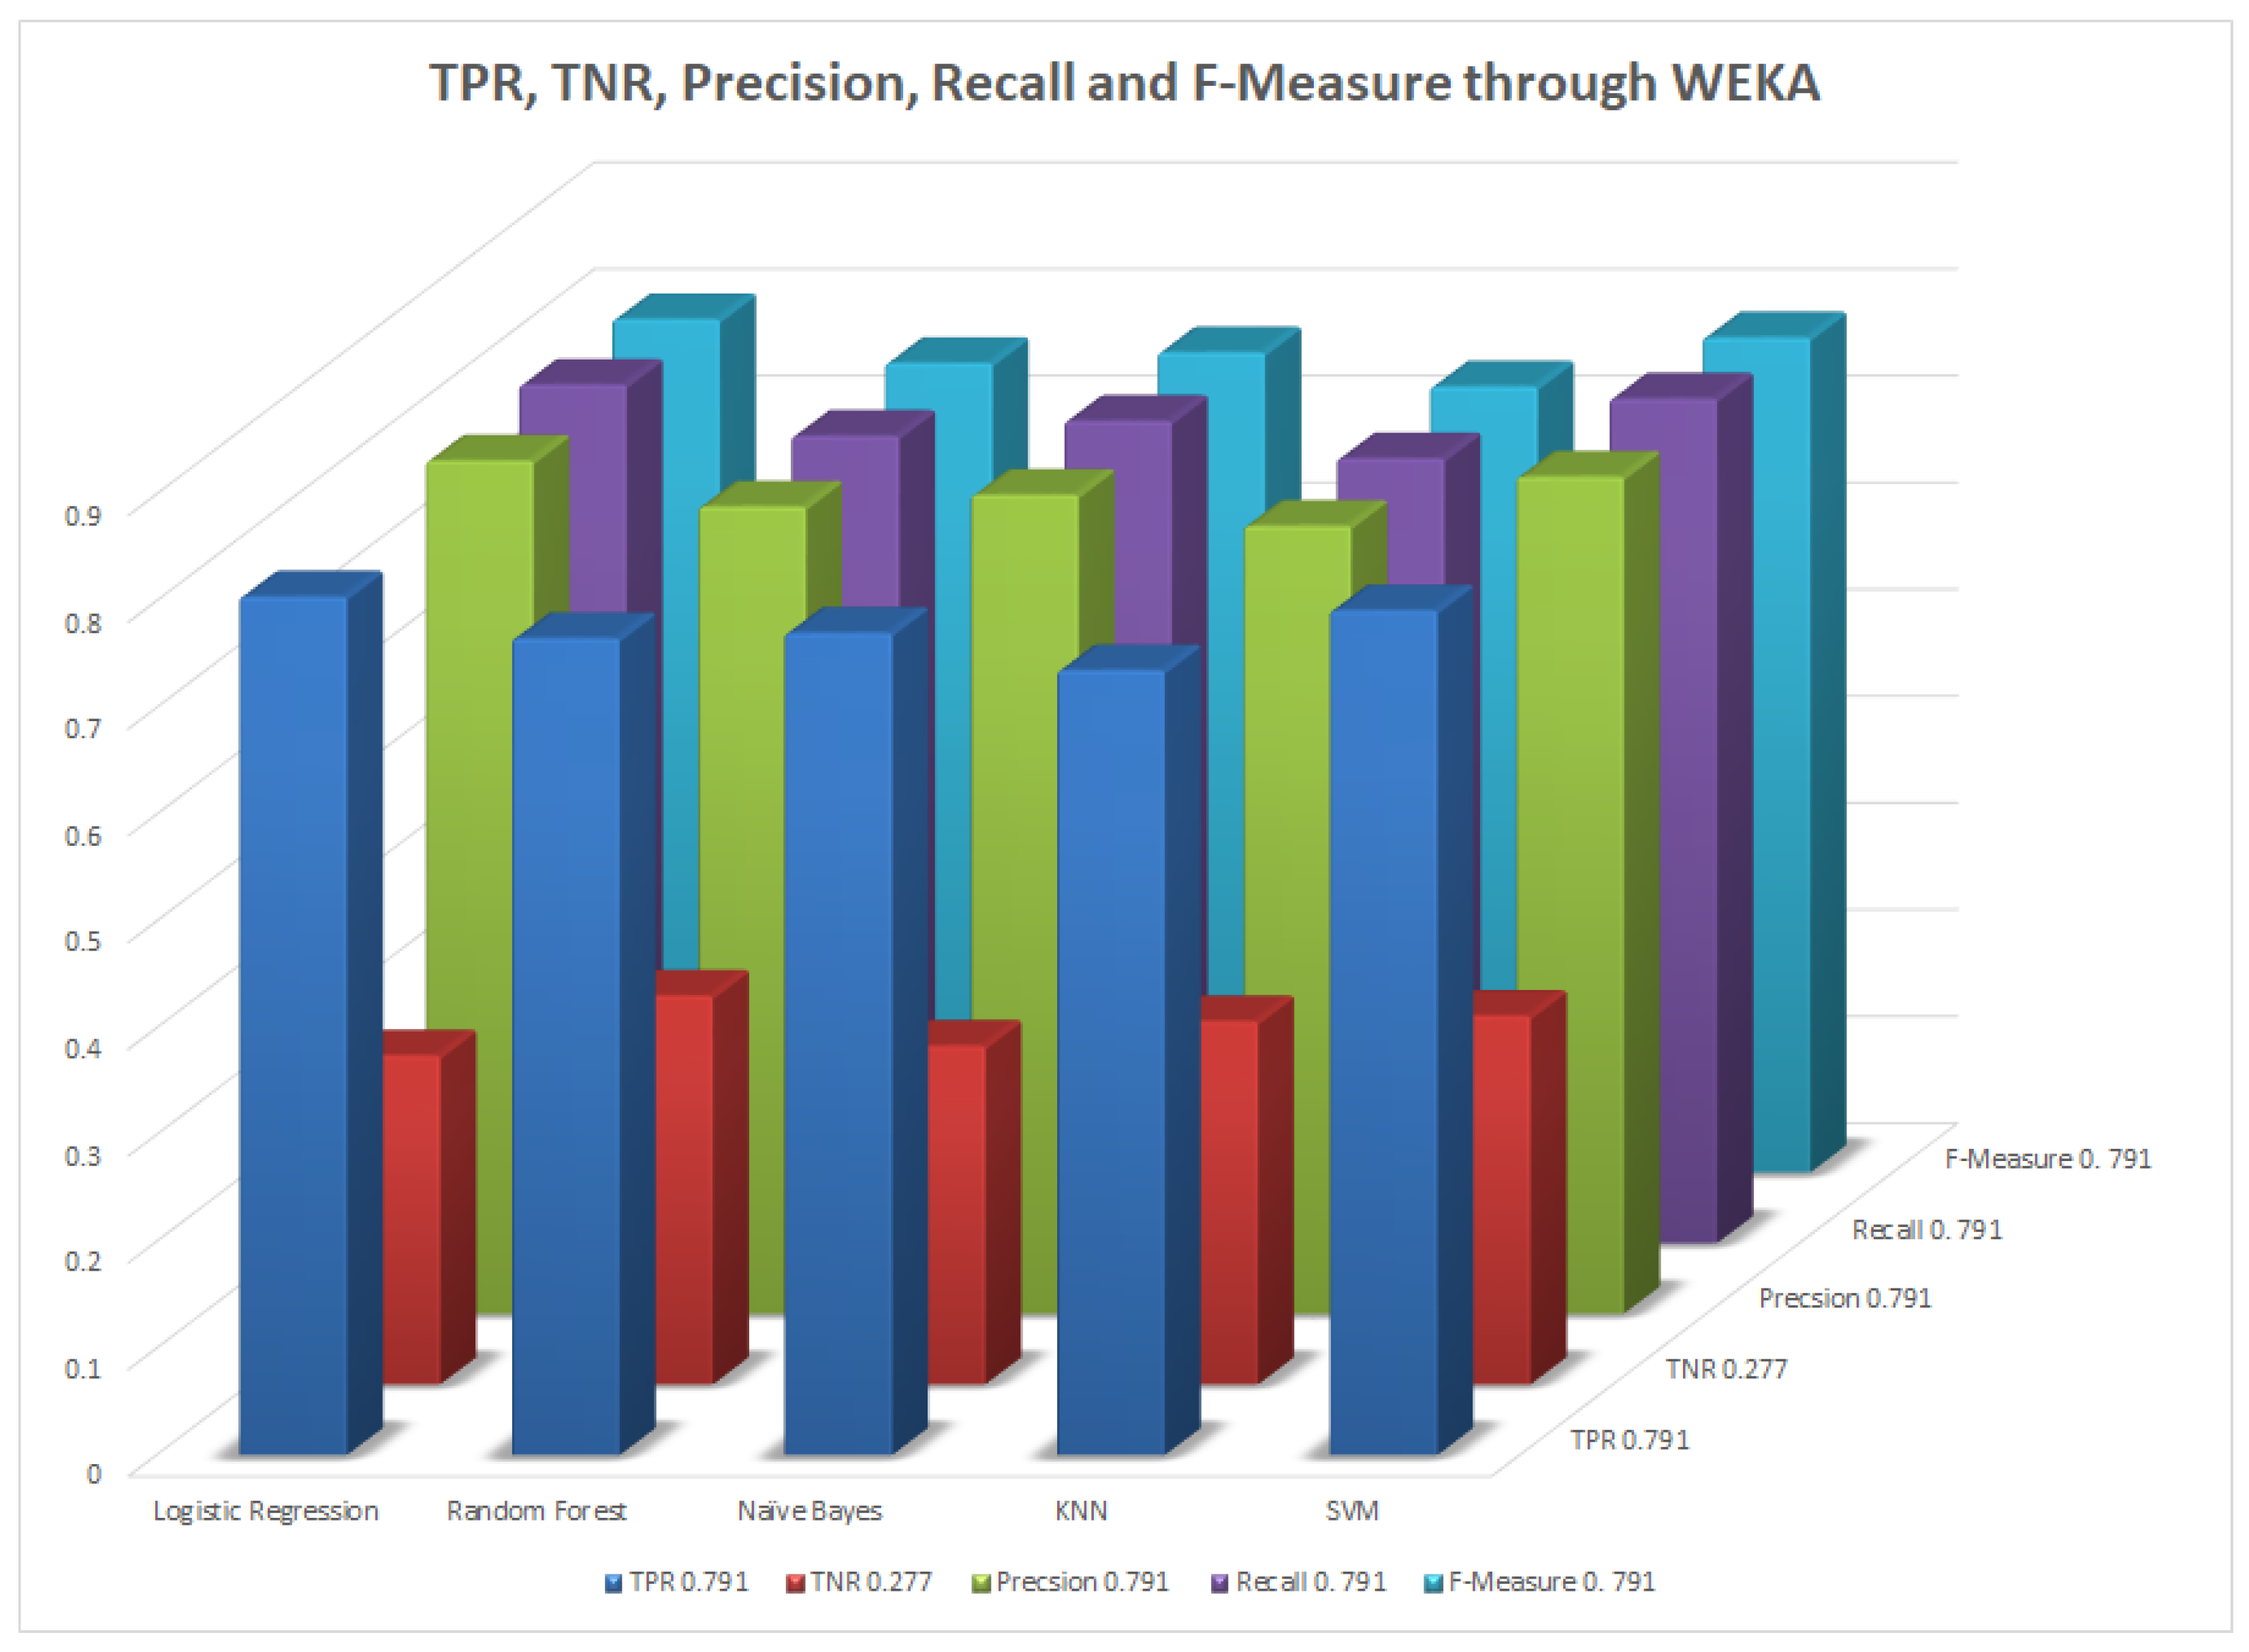
4.9. Performance Metrics
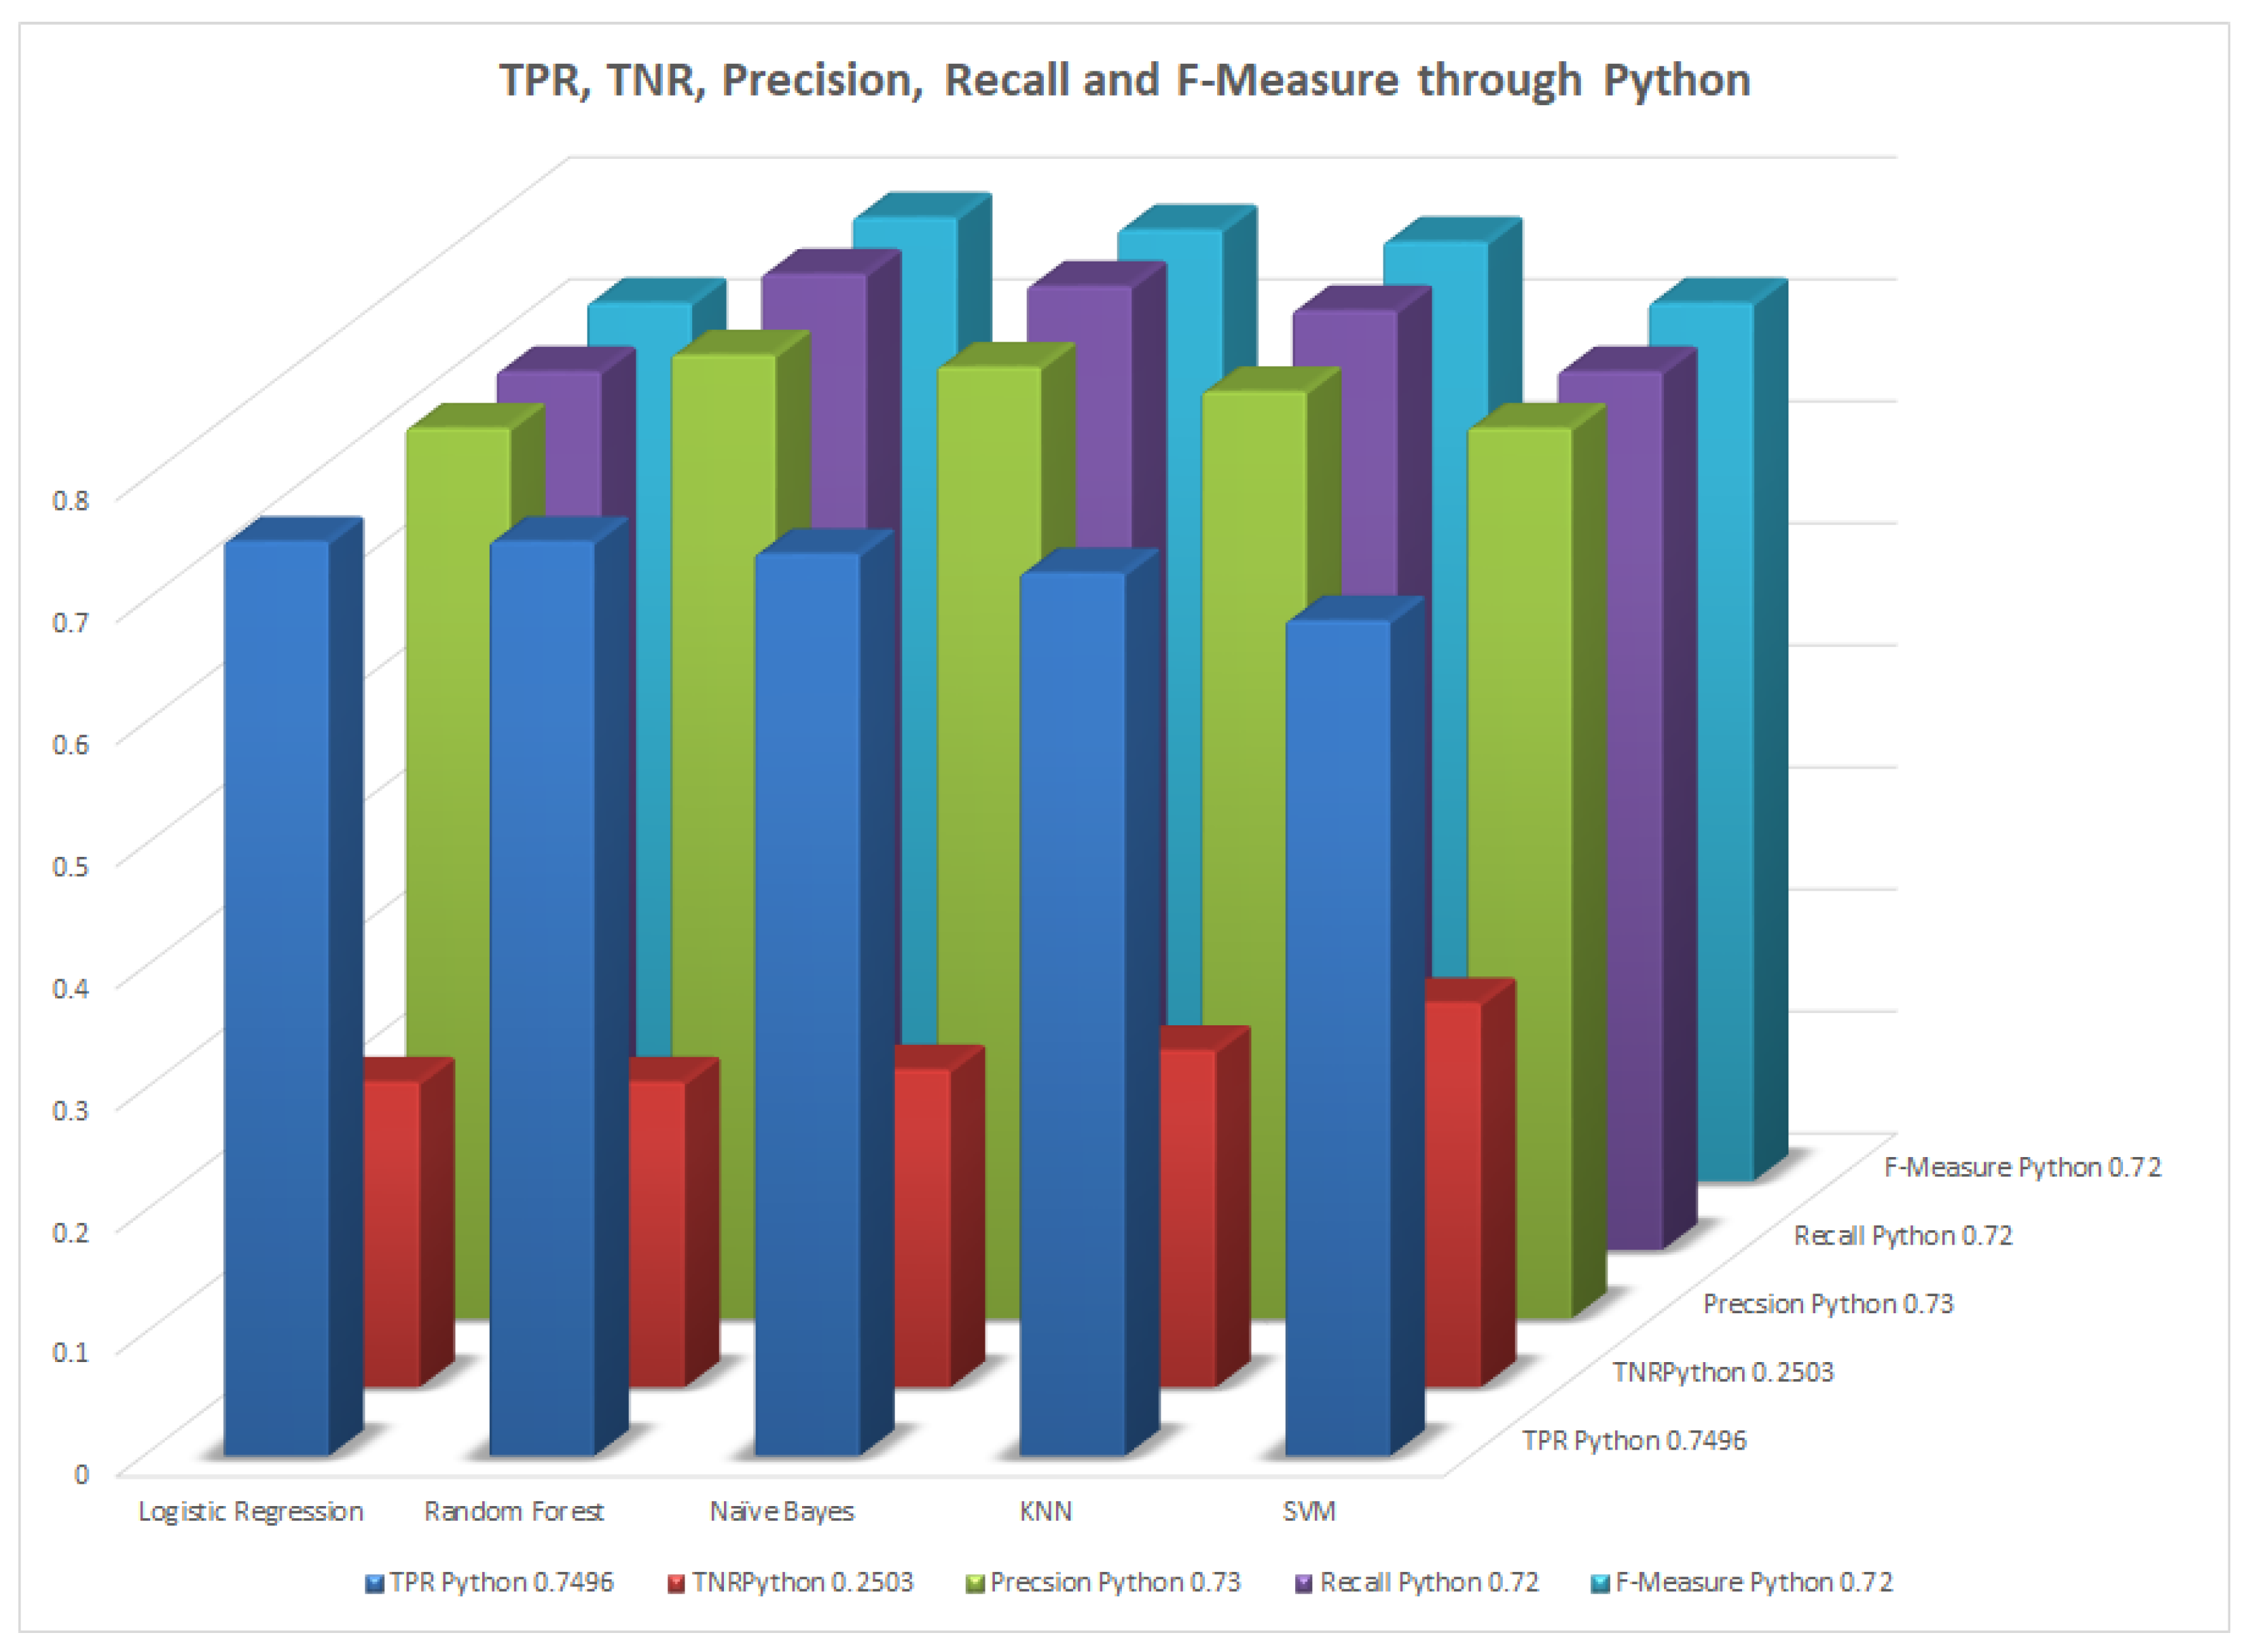
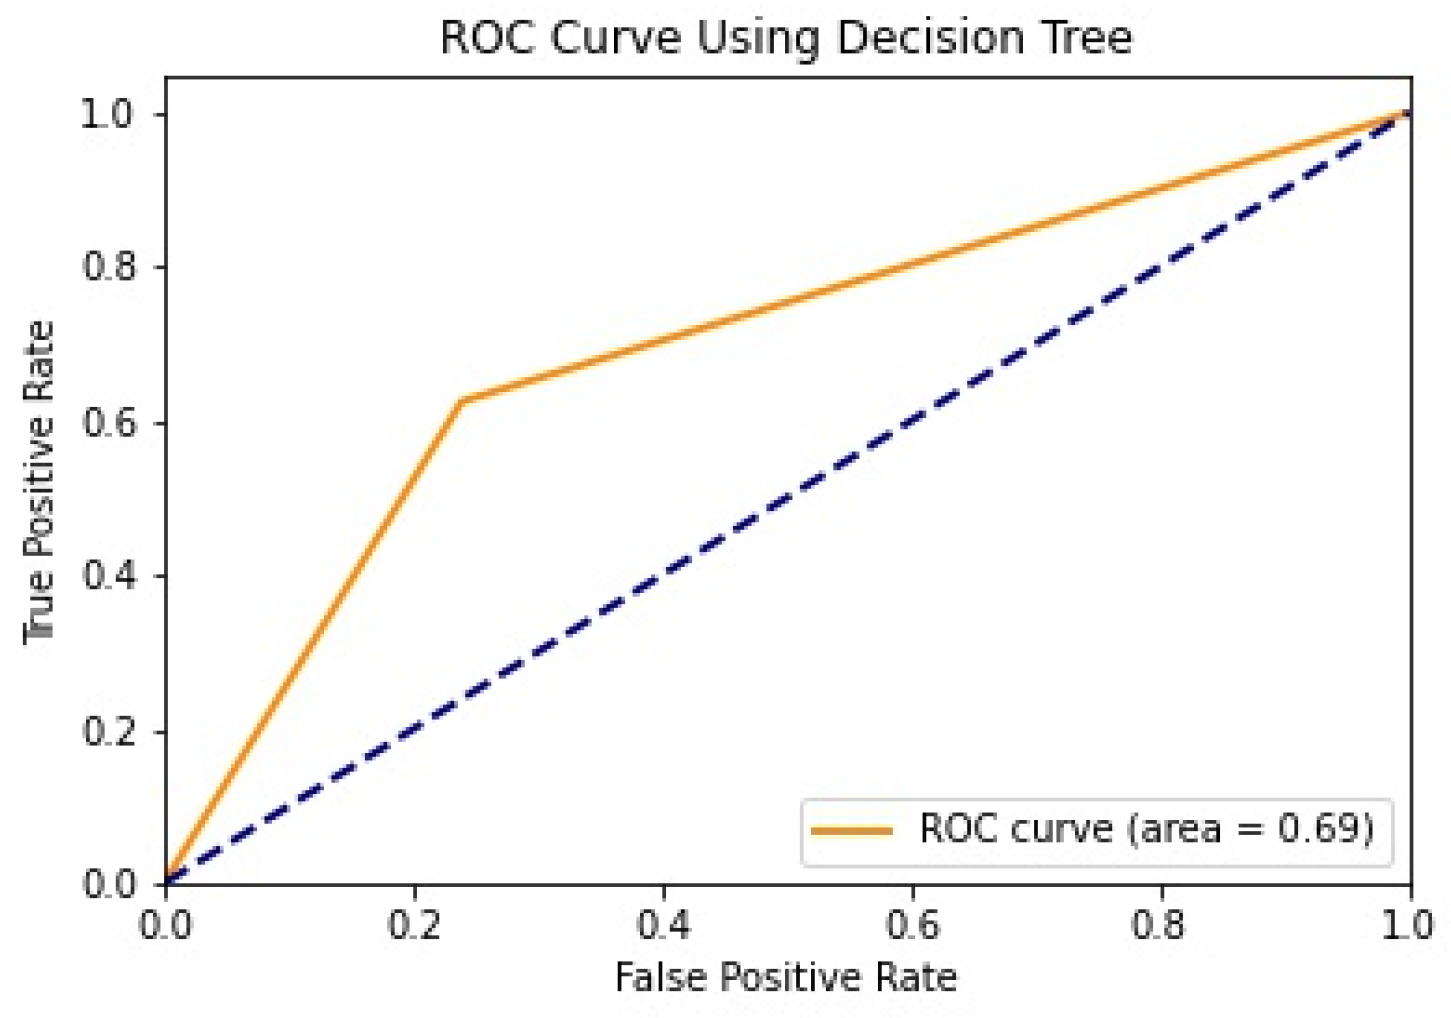
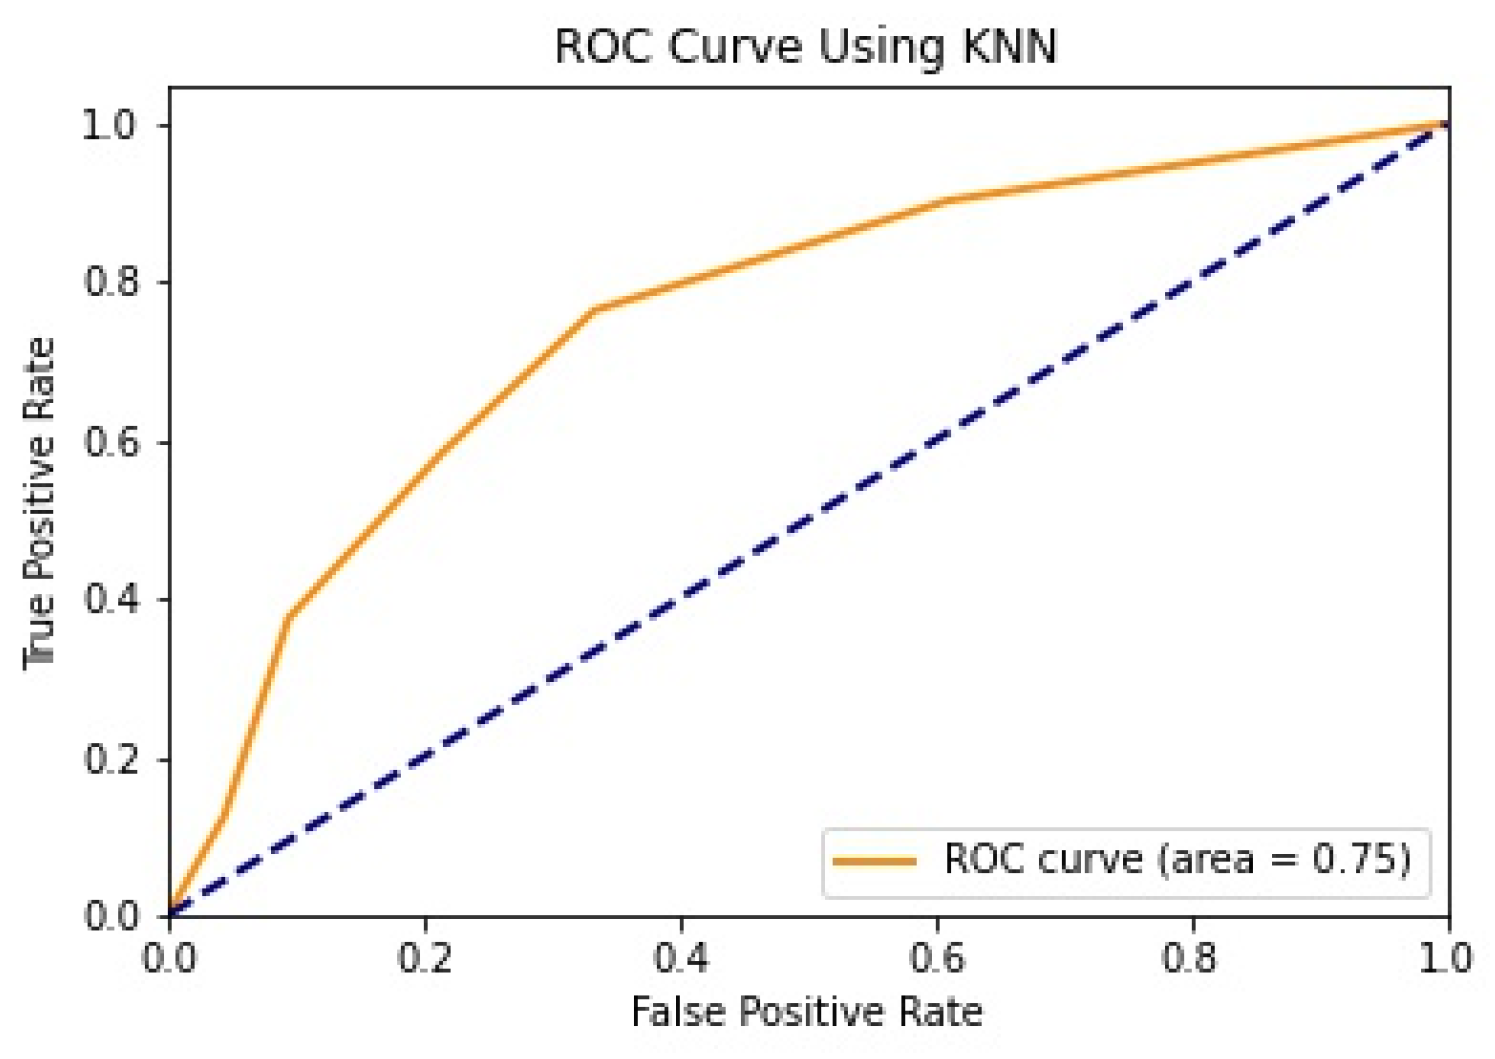
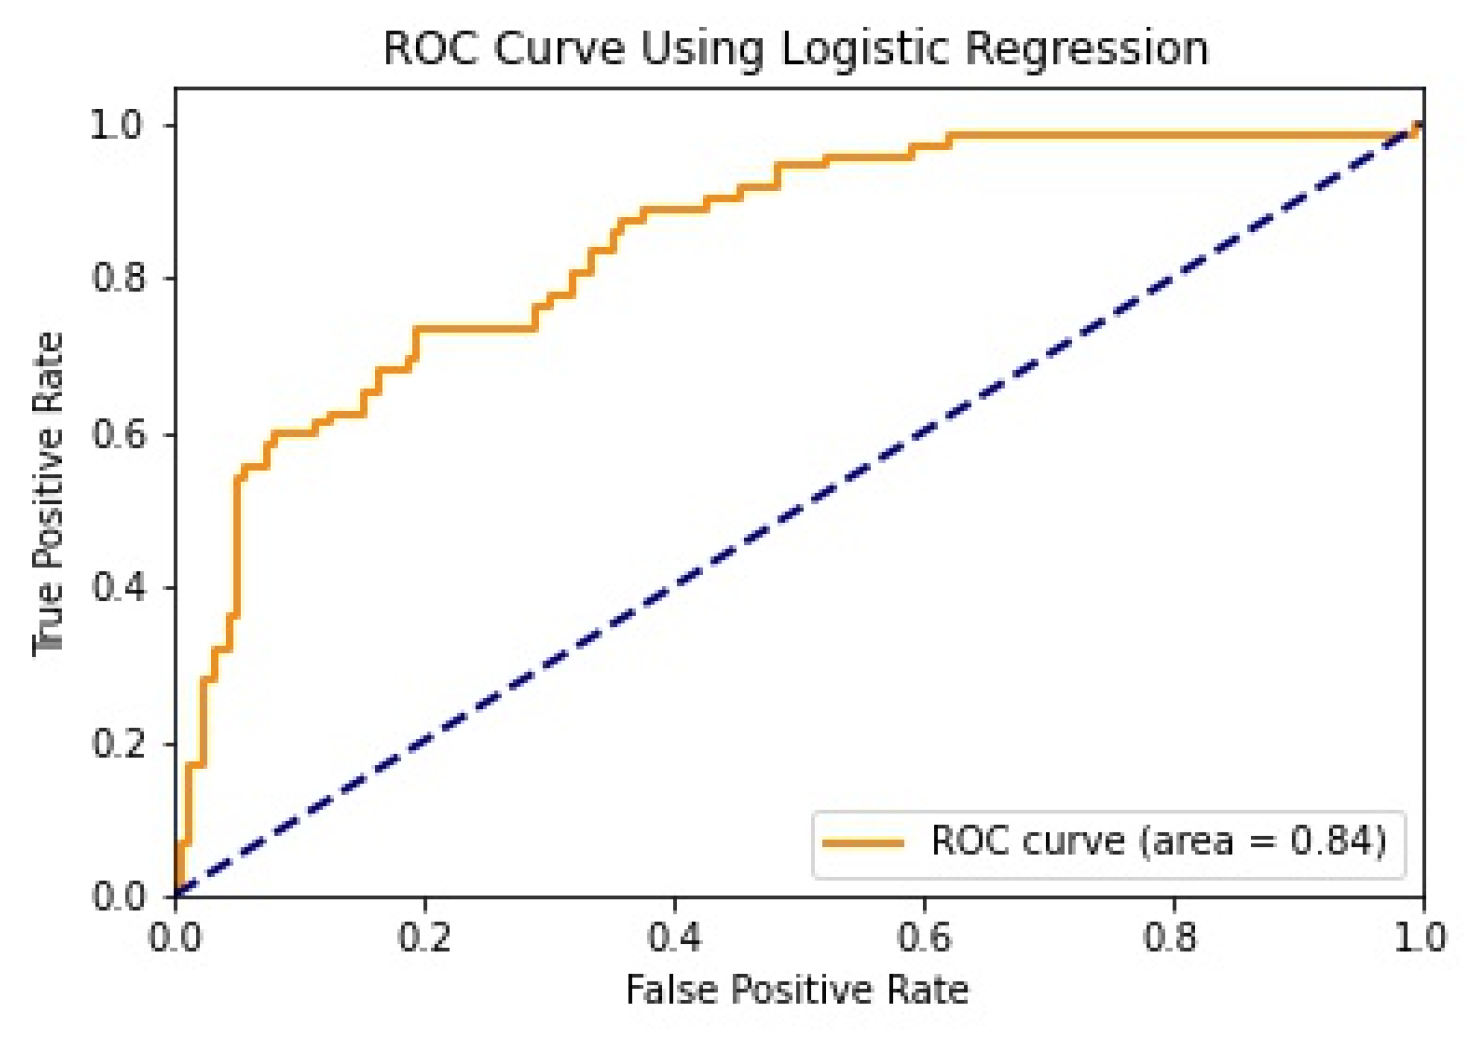
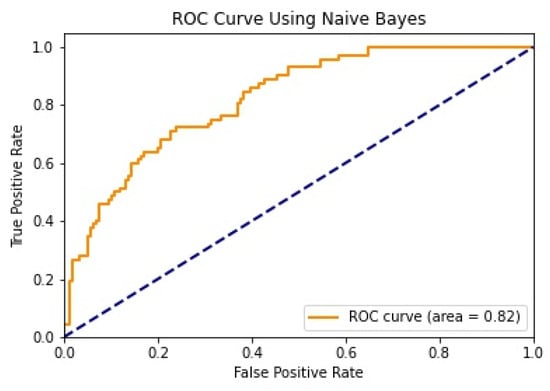
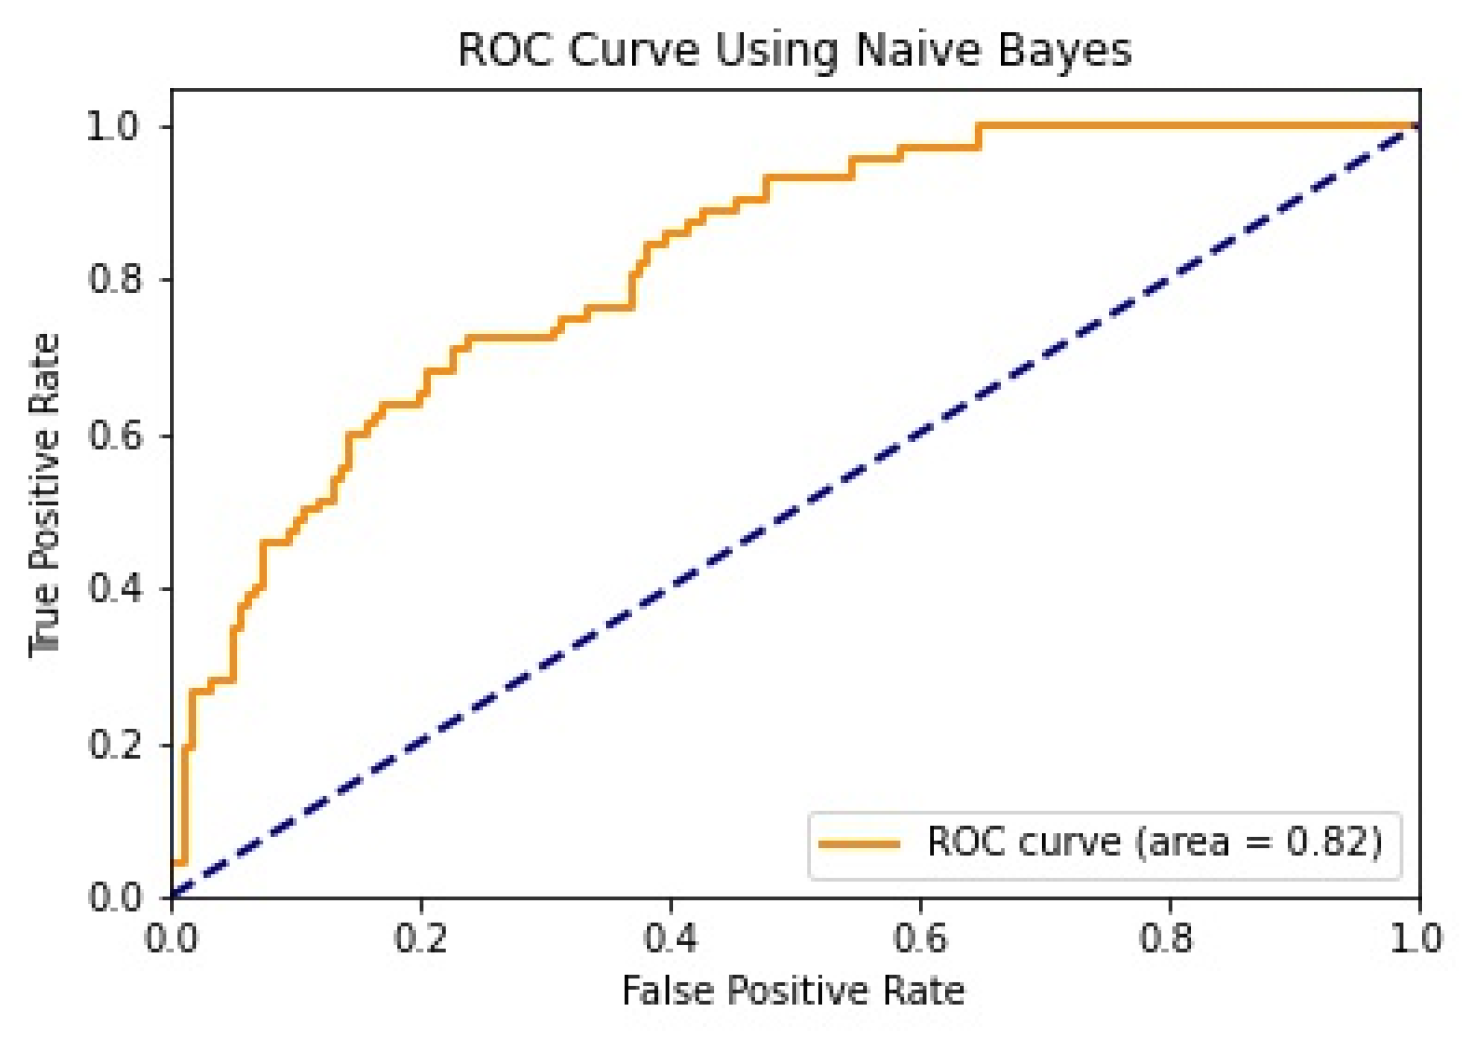
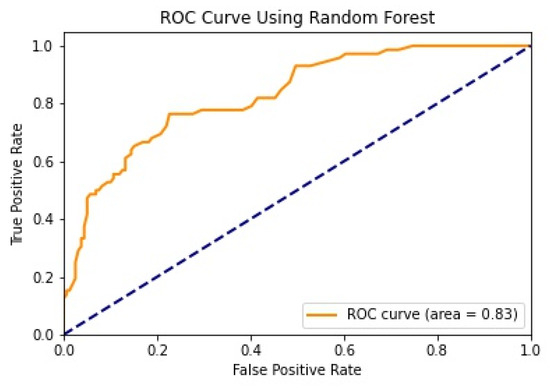
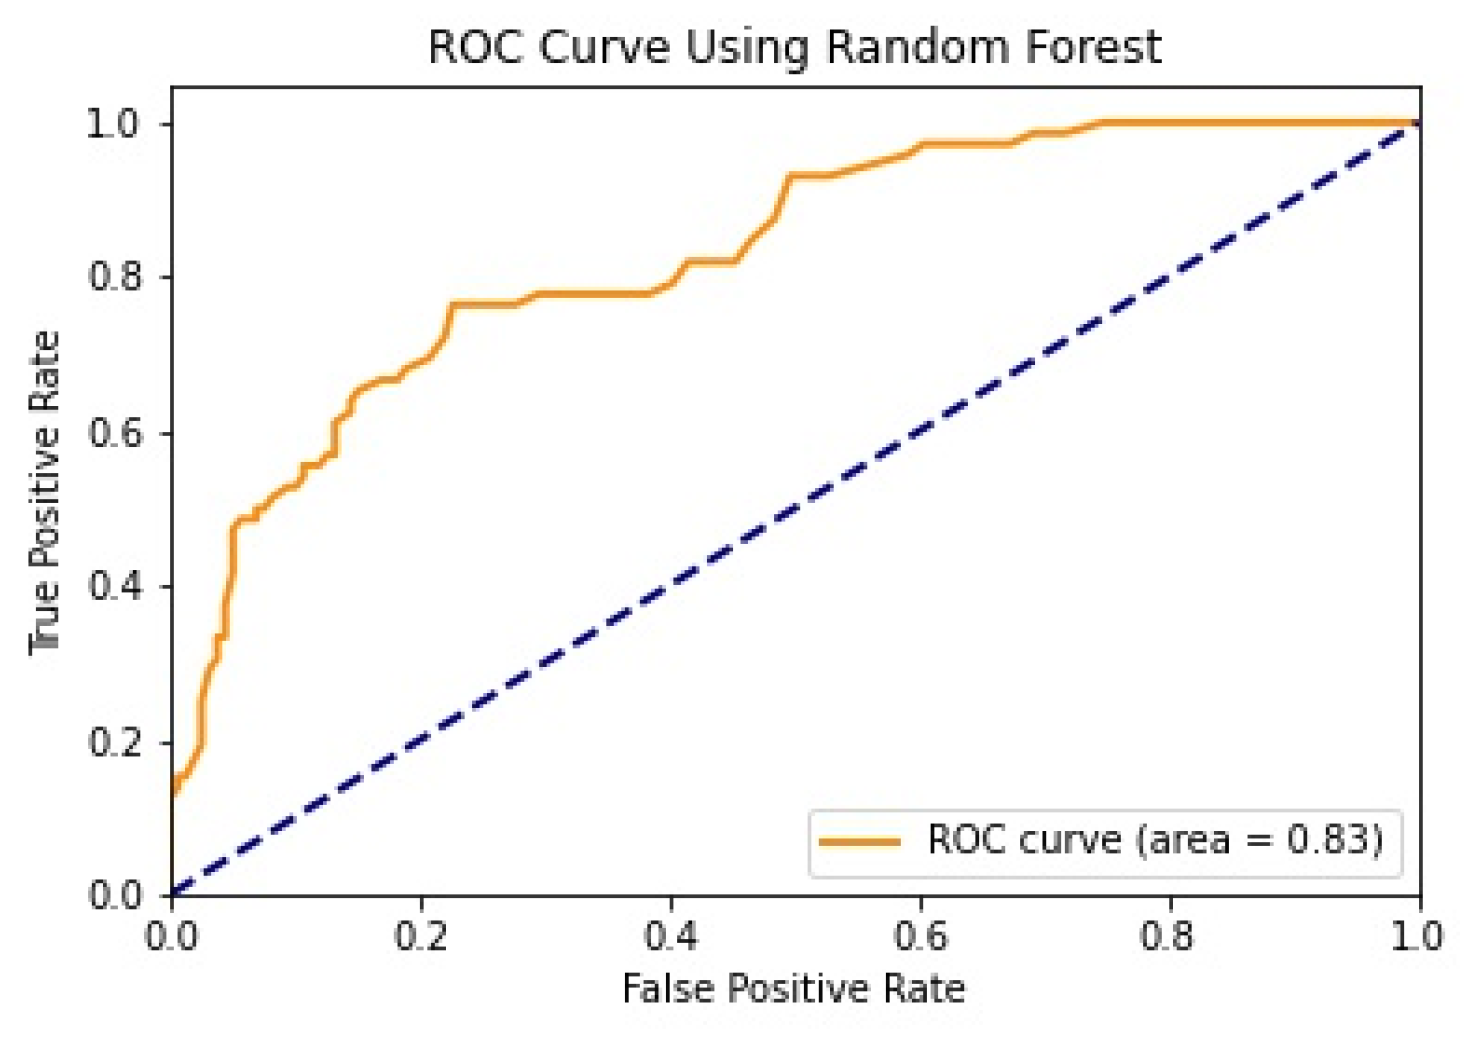
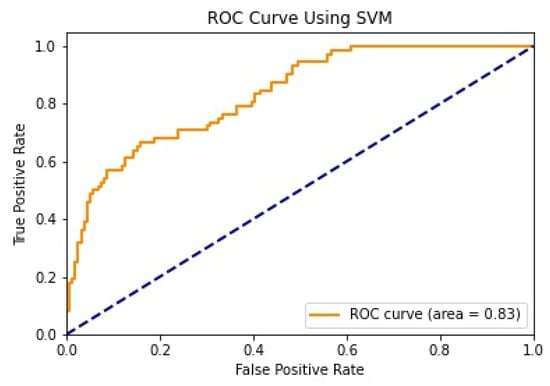
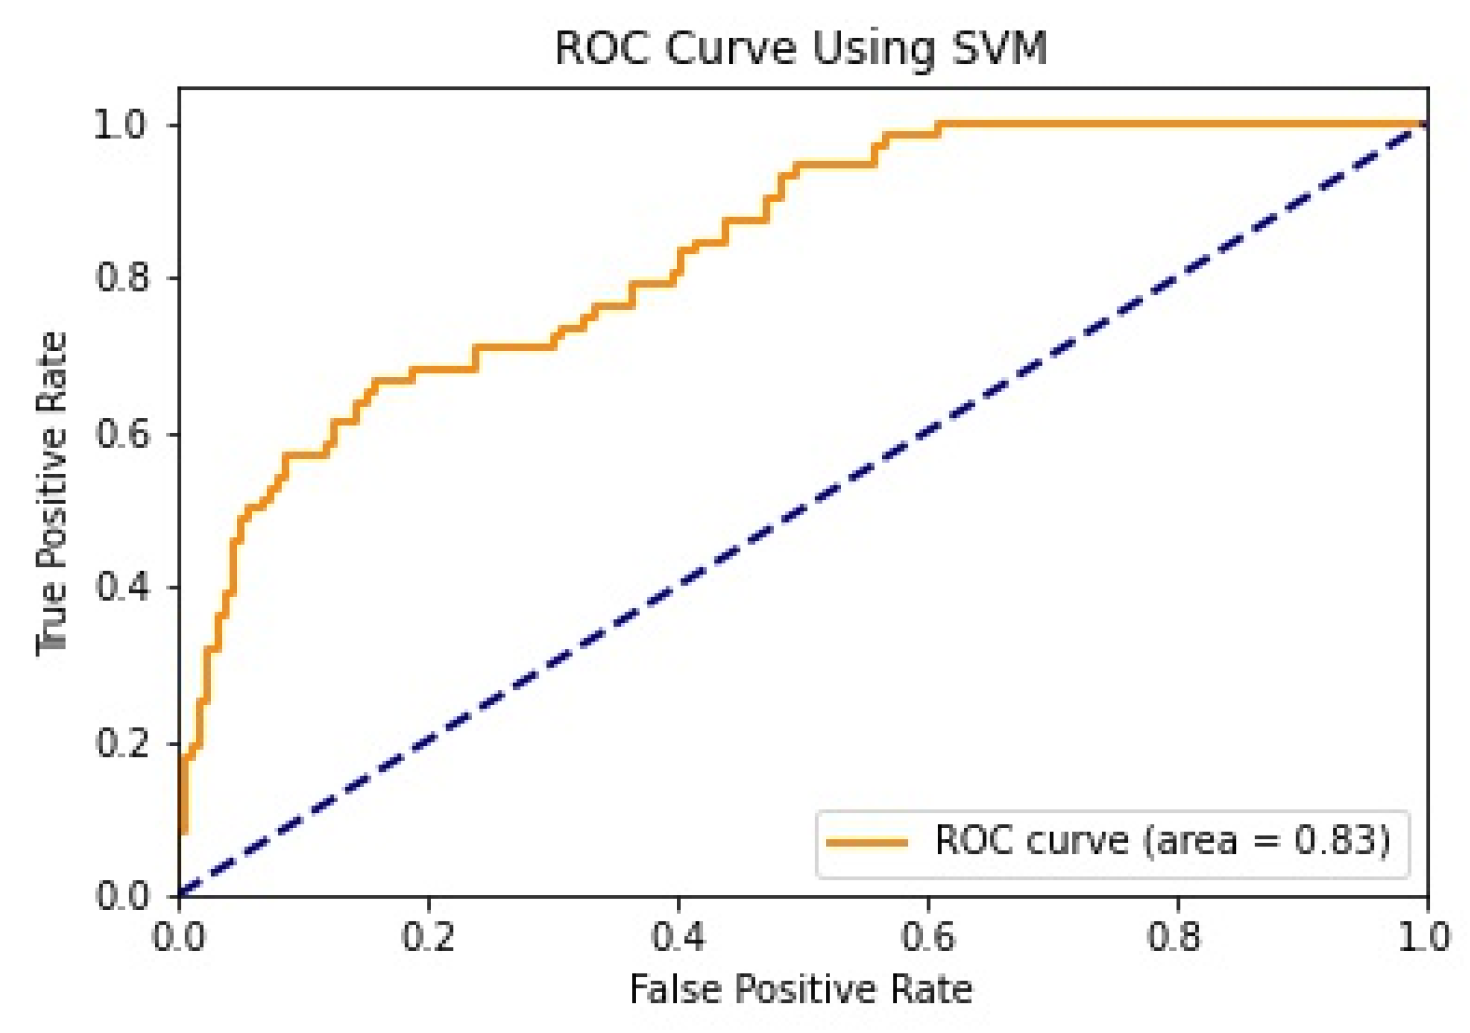
We mentioned some important errors in our research paper, which are shown in the form of tables and graphs. The true positive rate (TPR) and the true negative rate (TNR) are performance metrics used in machine learning, especially in the context of binary classification problems [35]. They provide insight into the accuracy of model predictions for positive and negative samples. An important metric used to evaluate exactness is precision. Recall shows what percentage of occurrences were really categorized as belonging to a particular class. The F-measure score, which is the weighted average (harmonic mean) of the accuracy and memory results, may be obtained by combining the two metrics of precision and recall, and it was used to predict the sample [13]. The following performance metrics are shown in Table 37 and Table 38 along with Figure 4, Figure 5, Figure 6, Figure 7, Figure 8, Figure 9, Figure 10 and Figure 11 respectively along with ROC curve graphs of all implemented classification algorithms.
Table 37.
TPR, TNR, precision, recall, and F-measure through WEKA.
Table 38.
TPR, TNR, precision, recall, and F-measure through Python.
Figure 4.
Performance metric through WEKA.
Figure 5.
Performance metrics through Python.
Figure 6.
ROC curve using Decision Tree.
Figure 7.
ROC curve using KNN.
Figure 8.
ROC curve using Logistic Regression.
Figure 9.
ROC curve using Naïve Bayes.
Figure 10.
ROC curve using Random Forest.
Figure 11.
ROC curve using SVM.
5. Conclusions
Diabetes is a complex medical disease that affects how the body uses glucose, a form of sugar that is the body’s primary fuel source. Diabetes results when our body is unable to make insulin or is unable to use the insulin produced by our body. According to 2017 statistics, 425 million people worldwide are suffering from diabetes. Diabetes causes 2 to 5 million deaths worldwide each year. By 2045, this is expected to increase to 629 million [36]. Type 1 diabetes, Type 2 diabetes, and gestational diabetes are the three main subtypes of diabetes. In this paper, we studied and tried to predict diabetes using six different classification algorithms applied to the PIMA diabetes dataset. We implemented and evaluated the results. The toolsets we used were WEKA, Python libraries like MATLAB, and Juypter Notebook. The main objective of our research work was to predict diabetes and select the algorithm that has the highest accuracy, such as Logistic Regression (81%), Decision Tree (80.10%), and SVM (80%). It has more than one calculated error, accuracy, precision, and F-measure. Finally, the study findings have important implications and offer benefits to various groups, including patients, healthcare providers, public health agencies, researchers, and insurance companies. The use of web-based diabetes prediction tools has the potential to provide timely support and treatment to at-risk individuals, leading to improved health outcomes and reduced healthcare costs. In the future, we aim to develop a complete web-based application with a medical module, user notification, and live chat box, and also aim to provide an Android application. We will also investigate the performance of the system and train some better accuracy algorithms.
Author Contributions
Conceptualization, Z.S. and W.Z.; methodology, W.A. and I.U.H.; software, Z.S.; validation, M.H.A.-A., Y.Y.G. and A.A.; formal analysis, G.H.; investigation, Z.S., M.H.A.-A. and A.A.; resources, Y.Y.G. and G.H.; data curation, W.Z., W.A. and I.U.H.; writing—original draft preparation, Z.S., W.Z., W.A. and I.U.H.; writing—review and editing, G.H., M.H.A.-A., Y.Y.G. and A.A; visualization, Z.S. and G.H.; supervision, G.H.; project administration, M.H.A.-A., Y.Y.G. and A.A.; funding acquisition, A.A. All authors have read and agreed to the published version of the manuscript.
Funding
This research was financially supported by the Deanship of Scientific Research at King Khalid University under research grant number (R.G.P.2/549/44).
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
Not applicable.
Conflicts of Interest
The authors declare no conflict of interest.
References
- Marx, V. Biology: The big challenges of big data. Nature 2013, 498, 255–260. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Mattmann, C.A. Computing: A vision for data science. Nature 2013, 493, 473–475. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Shetty, D.; Rit, K.; Shaikh, S.; Patil, N. Diabetes disease prediction using data mining. In Proceedings of the 2017 International Conference on Innovations in Information, Coimbatore, India, 17–18 March 2017. [Google Scholar]
- Archive. ICS. UCI. EDU. UCI Machine Learning Repository: Diabetes Data Set. 2020. Available online: https://archive.ics.uci.edu/ml/datasets/diabetes (accessed on 7 July 2023).
- Sisodia, D.; Sisodia, D.S. Prediction of Diabetes using Classification Algorithms. Procedia Comput. Sci. 2018, 132, 1578–1585. [Google Scholar] [CrossRef] [Scilit]
- Steffi, J.; Balasubramanian, R.; Kumar, M.K.A. Predicting Diabetes Mellitus using Data Mining Techniques. Int. J. Eng. Dev. Res. 2018, 6, 460–467. [Google Scholar]
- Kaur, G.; Chhabra, A. Improved J48 Classification algorithms for the Prediction of Diabetes. Int. J. Comput. Appl. 2014, 98, 22. [Google Scholar] [CrossRef] [Scilit]
- Rout, M.; Kaur, A. Prediction of Diabetes Based on Data Mining Techniques. Think India J. 2019, 22, 3743–3750. [Google Scholar]
- Varma, K.M.; Panda, B.S. Comparative analysis of Prediction Diabetes Using Machine Learning Techniques. J. Emerg. Technol. Innov. 2019, 6, 522–530. [Google Scholar]
- Wu, H.; Yang, S.; Huang, Z.; He, J.; Wang, X. Type 2 diabetes mellitus prediction model based on data mining. Inform. Med. Unlocked 2018, 10, 100–107. [Google Scholar] [CrossRef] [Scilit]
- Suresh, K.; Obulesu, O.; Ramudu, B.V. Diabetes Prediction using Machine Learning Techniques. HELIX 2020, 10, 136–142. [Google Scholar]
- Das, H.; Naik, B.; Behera, H.S. Classification of diabetes mellitus disease (DMD): A data mining (DM) approach. In Progress in Computing, Analytics and Networking; Springer: Singapore, 2018; pp. 539–549. [Google Scholar]
- Abdulhadi, N.; Al-mousa, A. Diabetes Detection Using Machine Learning Classification Methods. In Proceedings of the 2021 International Conference on Information Technology (ICIT), Amman, Jordan, 14–15 July 2021; pp. 350–354. [Google Scholar]
- Chou, C.-Y.; Hsu, D.-Y.; Chou, C.-H. Predicting the Onset of Diabetes with Machine Learning Methods. J. Pers. Med. 2023, 13, 406. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Alam, T.M.; Iqbal, M.A.; Ali, Y.; Wahab, A.; Ijaz, S.; Baig, T.I.; Hussain, A.; Malik, M.A.; Raza, M.M.; Ibrar, S.; et al. A model for early prediction of diabetes. Inform. Med. Unlocked 2019, 16, 100204. [Google Scholar] [CrossRef] [Scilit]
- Kumari, M.; Vohra, R.; Arora, A. Pre- diction of diabetes using Bayesian Network. Int. J. Comput. Sci. Inf. Technol. 2014, 5, 5174–5178. [Google Scholar]
- Mir, A.; Dhage, S.N. Diabetes Disease Prediction Using Machine Learning on Big Data of Healthcare. In Proceedings of the 2018 Fourth International Conference on Computing Communication Control and Automation (ICCUBEA), Pune, India, 16–18 August 2018; pp. 1–6. [Google Scholar]
- Naz, H.; Ahuja, S. Deep learning approach for diabetes prediction using PIMA Indian dataset. J. Diabetes Metab. Disord. 2020, 19, 391–403. [Google Scholar] [CrossRef] [Scilit]
- Iyer, A.; Jeyalatha, S.; Sumbaly, R. Diagnosis of Diabetes Using Classification Mining Techniques. Int. J. Data Min. Knowl. Manag. Process 2015, 5, 1–14. [Google Scholar] [CrossRef] [Scilit]
- Diego, S.; Jolla, L. “Weka”, SourceForge. 2020. Available online: https://sourceforge.net/projects/weka/ (accessed on 7 July 2023).
- Cs.aucland.ac.nz. 2020. Available online: https://www.cs.auckland.ac.nz/courses/compsci367s1c/tutorials/IntroductionToWeka.pdf/ (accessed on 7 July 2023).
- Koehrsen, W. Precision and Recall: How to Evaluate Your Classification Model. 2021. Available online: https://builtin.com/data-science/precision-and-recall (accessed on 7 July 2023).
- Posonia, A.M.; Vigneshwari, S.; Rani, D.J. Machine Learning Based Diabetes Prediction Using Decision Tree J48. In Proceedings of the 3rd International Conference on Intelligent Sustainable Systems (ICISS), Thoothukudi, India, 3–5 December 2020; pp. 498–502. [Google Scholar]
- Jaiswal, S. Machine Learning Decision Tree Classification Algorithm-Javatpoint. 2020. Available online: https://www.javatpoint.com/machine-learning-decision-tree-classification-algorithm (accessed on 7 July 2023).
- Naseem, R.; Shaukat, Z.; Irfan, M.; Shah, M.A.; Ahmad, A.; Muhammad, F.; Glowacz, A.; Dunai, L.; Antonino-Daviu, J.; Sulaiman, A. Empirical Assessment of Machine Learning Techniques for Software Requirements Risk Prediction. Electronics 2021, 10, 168. [Google Scholar] [CrossRef] [Scilit]
- Navlani, A. (Tutorial) Understanding Logistic REGRESSION in PYTHON. DataCampCommunity. 2020. Available online: https://www.datacamp.com/community/tutorials/understanding-logistic-regression-python/ (accessed on 7 July 2023).
- Chen, J.; Li, K.; Tang, Z.; Bilal, K.; Yu, S.; Weng, C.; Li, K. A Parallel Random Forest Algorithm for Big Data in a Spark Cloud Computing Environment. IEEE Trans. Parallel Distrib. Syst. 2017, 28, 919–933. [Google Scholar] [CrossRef] [Scilit]
- Bui, H. ROC Curve Transforms the Way We Look at a Classification Problem. Medium. 2020. Available online: https://towardsdatascience.com/a-simple-explanation-of-the-roc-curve-and-auc-64db32d75541/ (accessed on 7 July 2023).
- Navlani, A. KNN Classification Using Scikit-Learn. DataCamp Community. 2020. Available online: https://www.datacamp.com/community/tutorials/k-nearest-neighbor-classification-scikit-learn (accessed on 7 July 2023).
- Navlani, A. (Tutorial) Support Vector Machines (SVM) in Scikit-learn. DataCamp Community. 2020. Available online: https://www.datacamp.com/community/tutorials/svmclassification-scikit-learn-python/ (accessed on 7 July 2023).
- Santhanam, T.; Padmavathi, M. Application of K-Means and Genetic Algorithms for Dimension Reduction by Integrating SVM for Diabetes Diagnosis. Procedia Comput. Sci. 2015, 47, 76–83. [Google Scholar] [CrossRef] [Scilit]
- Wu, X.; Kumar, V.; Ross Quinlan, J.; Ghosh, J.; Yang, Q.; Motoda, H.; McLachlan, G.J.; Ng, A.; Liu, B.; Yu, P.S.; et al. Top 10 algorithms in data mining. Knowl. Inf. Syst. 2007, 14, 1–37. [Google Scholar] [CrossRef] [Scilit]
- Piatetsky-Shapiro, G. The Best Metric to Measure Accuracy of Classification Models—Kdnuggets. Kdnuggets. 2020. Available online: https://www.kdnuggets.com/2016/12/best-metric-measure-accuracy-classification-models.html/2/ (accessed on 7 July 2023).
- Shaukat, Z.S.; Naseem, R.; Zubair, M. A Dataset for Software Requirements Risk Prediction. In Proceedings of the 2018 IEEE International Conference on Computational Science and Engineering (CSE), Bucharest, Romania, 29–31 October 2018; pp. 112–118. [Google Scholar] [CrossRef] [Scilit]
- Chicco, D.; Jurman, G. The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation. BMC Genom. 2020, 21, 6. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Kalyankar, G.D.; Poojara, S.R.; Dharwadkar, N.V. Predictive Analysis of Diabetic Patient Data Using Machine Learning and Hadoop. In Proceedings of the 2017 International Conference on I-SMAC (IoT in Social, Mobile, Analytics and Cloud) (I-SMAC), Palladam, India, 10–11 February 2017. [Google Scholar]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2023 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).