


Abstract
Effectively modeling software failure behavior is crucial for reliability assessment and planning of releases. However, many current software reliability growth models assume that failures are independent and fault detection mechanisms are simplified. However, these assumptions may not accurately represent real-world testing environments. This study introduces a novel Nonhomogeneous Poisson Process (NHPP)-based Software Reliability Growth Model (SRGM) that includes dependent failure behavior and exponentially decaying fault detection rates to better reflect the software debugging process. The proposed model was validated using real failure datasets and compared with 17 existing models. The performance of the model was assessed using various goodness-of-fit criteria, such as errors, prediction accuracy, and metrics based on information theory. To provide a more thorough evaluation, a multi-criteria decision-making approach was used to rank the competing models based on their overall performance. Furthermore, a one-at-a-time sensitivity analysis was conducted to examine how the initial values of the parameters affected the model’s behavior. These findings indicate that the sensitivity of the model to this parameter varies depending on the dataset used. The results indicate that the proposed model achieved superior performance across multiple evaluation criteria and consistently obtained the best overall ranking under the integrated multi-criteria framework. In Dataset 1, the proposed model achieved the best performance in most goodness-of-fit criteria, whereas in Dataset 2 it produced the best results across all twelve evaluation criteria. The results show that the proposed model offers improved or competitive performance compared to existing models and provides greater flexibility in capturing complex failure processes within software systems.
Keywords:
dependent failures; exponentially decaying fault detection rate function; multi-criteria decision-making approach; sensitivity analysis MSC:
68N05; 68N30; 90B25
1. Introduction
Software systems have become progressively more intricate and are extensively used in large-scale, industrial, and safety-critical environments. As software complexity has increased, accurate reliability evaluation and failure prediction have become crucial for aiding testing methodologies, release decisions, and maintenance planning. To address this issue, Software Reliability Growth Models (SRGMs), particularly those based on a Nonhomogeneous Poisson Process (NHPP), have been thoroughly examined owing to their robust mathematical underpinnings and analytical manageability [1,2].
In modern software systems, reliability failures often arise in highly interconnected environments where software components continuously interact through shared libraries, cloud services, and distributed architecture. In such systems, assuming that failures occur independently may lead to biased reliability prediction and inaccurate release decisions. For example, a defect in a shared software component may simultaneously affect multiple functions. Also, the complex interactions among software components can create dependency relationships among failures, where one failure may influence the occurrence of following failures. At the same time, as software testing progresses, the remaining faults often become increasingly difficult to detect, causing changes in the fault detection behavior over time. Therefore, motivated by these practical characteristics, simultaneous consideration of failure dependency and time-dependent fault detection becomes important for more accurately representing software reliability growth processes.
Early and classical NHPP-based SRGMs, including the Goel and Okumoto model and the S-shaped model, typically assume that software failures occur independently. These models also operate under the assumption of perfect debugging, implying that the identified faults are completely removed without influencing subsequent failures [1,3]. However, these assumptions frequently do not hold true in modern software systems, where failures tend to be interrelated, rather than occurring as isolated incidents. A review by Haque and Ahmad further emphasized that unrealistic assumptions, uncertainty factors, and the lack of model flexibility remain major challenges in the application of traditional SRGMs [4].
In practical software development environments, failures often demonstrate dependent failure behaviors. Initially, multiple failures can stem from shared code components or common functional modules, leading to repeated failures until the root cause is eliminated [5]. Furthermore, fault propagation between interacting modules can result in cascading failures, in which an initial failure increases the chances of subsequent failures [6]. In addition, imperfect debugging, as studied by Pham et al. [7], suggests that detected faults may not be fully eliminated or could even create new faults, thus fostering dependency among failures. Finally, the intricate interactions among modules in large-scale systems further intensify failure dependency. Although failure propagation concepts have been extensively studied in physical and network systems, software failure dependency possesses distinct characteristics. Unlike physical systems, where failures may arise from random physical processes, software failures are generally associated with deterministic logical interactions among modules. Similar cascading behaviors have also been investigated in cyber-physical systems, where dependency structures and network interactions influence failure propagation mechanisms [8]. These studies provide useful methodological insight into dependency analysis and further highlight the importance of considering dependency effects in software reliability growth modeling.
To ease the assumption of independence, several studies have proposed modifications to classical SRGMs. Pham and Zhang [9,10] presented generalized NHPP-based SRGMs to address the variability in operational environments, and Pham et al. [7] specifically integrated the imperfect debugging processes. Although dependent failures, imperfect debugging, and delayed fault detection are related concepts, they describe different aspects of software reliability growth. Imperfect debugging primarily considers situations where debugging activities may fail to eliminate faults completely or may introduce additional faults into the system. Delayed detection models focus on time lags between fault occurrence and fault identification during software testing. In contrast, dependent failure models assume that software failures interact due to shared components and fault propagation effects. Therefore, the proposed model primarily addresses failure interaction characteristics rather than explicitly modeling fault introduction or delayed detection mechanisms.
In recent years, the importance of time-dependent fault detection rates has been highlighted by the increase in open-source software (OSS). OSS projects are distinct from closed industrial projects, revealing the limitations of SRGMs that assume a constant fault-detection rate. Consequently, sophisticated NHPP-based SRGMs that integrate time-dependent rates, coverage growth, imperfect debugging, and delayed fault detection have been proposed. For example, Wang et al. [11] introduced a Weibull-Weibull model specifically tailored for OSS big data projects, demonstrating significant enhancements in predictive accuracy compared with traditional models. Similarly, Wang et al. [12] developed multi-release SRGMs for OSS systems by considering the ongoing development of OSS through successive iterations.
In addition to the challenges associated with modeling, the rapid increase in the number of SRGMs has rendered model comparison and selection a significant concern in the analysis of software reliability. Numerous studies depend on a single measure of the goodness-of-fit accuracy, which can result in inconsistent conclusions when the models demonstrate varying strengths across different performance criteria. To address this limitation, multi-criteria decision-making methods offer a structured approach for incorporating multiple criteria into a cohesive assessment. Traditional multi-criteria decision-making methods have been extensively examined in the field of decision science [13,14]; however, their use in the evaluation of SRGMs remains relatively scarce.
Based on the preceding discussion, this study addresses the following research questions:
RQ1: How can dependent software failure behavior be incorporated into NHPP-based SRGMs to better represent practical software testing environments?
RQ2: Can an exponentially decaying fault detection mechanism effectively describe time-dependent fault detection behavior while maintaining model flexibility?
RQ3: To what extent can the proposed dependent failure NHPP SRGM improve fitting and predictive performance compared with traditional independent failure models?
Motivated by these findings, this study introduces a novel NHPP-based SRGM that specifically considers the dependent failure behavior. To facilitate a reliable comparison, an integrated multi-criteria evaluation framework was used, which included the Multi-Criteria Decision Method (MCDM), Multi-Criteria Decision Method using Ranking (MCDMR), Multi-Criteria Decision Method using Maximum (MCDMM), and Rank Euclidean Distance (RED). This framework allows the simultaneous assessment of various criteria related to accuracy, stability, and robustness, which offers a well-rounded foundation for model selection.
Moreover, to illustrate the general applicability of the proposed model and its evaluation, validation was performed using both a closed-type industrial software failure dataset and an OSS failure dataset. The inclusion of these two datasets guarantees that the proposed model is relevant across various software development contexts and is not confined to a particular data type.
The main contributions of this study are summarized as follows:
- A novel NHPP-based SRGM is proposed to capture the dependent failure behavior under an exponentially decaying fault-detection rate.
- A non-zero initial condition was incorporated to reflect practical testing situations in which fault detection may have started before the observation period.
- An integrated multi-criteria decision-making framework was employed to provide a robust and balanced evaluation of competing SRGMs.
- Extensive analyses were conducted on both industrial and OSS failure datasets to demonstrate the effectiveness and applicability of the proposed approach.
The remainder of this paper is organized as follows. Section 2 provides a comprehensive overview of SRGMs based on the NHPP, including an in-depth derivation of the proposed model and existing SRGMs that are commonly utilized. Section 3 outlines the study criteria. Section 4 introduces the two datasets utilized in this study and presents the analysis results of the parameter estimation for the respective models, a comparison of the goodness-of-fit test outcomes, and the sensitivity analysis results for the parameter . Finally, Section 5 concludes the study and explores potential directions for future research.
2. Novel SRGM
2.1. SRGM
A counting process counts the number of failures that occur up to time [5]. is said to be a Poisson process with a failure intensity if:
- The failure process, , has stationary independent increments.
- The number of failures in any time interval of length has a Poisson distribution with mean , that is:
- The initial condition is
This model is called a Homogeneous Poisson Process (HPP) indicating that the constant failure rate does not depend on the time but on the length of time interval s. To capture the changing aspects of software testing and fault removal, the constant failure rate in the HPP is extended to a time-dependent function , leading to the NHPP.
For the NHPP, the probability of exactly failures occurring during the time interval is given by Equation (1):
where denotes a counting process that follows the Poisson distribution with a time-dependent function . The function is a mean value function which is the integral of over the interval , as given in Equation (2). The function characterizes the instantaneous failure occurrence rate at time t.
In general, the value of an NHPP-based SRGM is obtained by solving the following differential equation [1]:
where denotes the expected total number of faults present in the software system at time , including both the initial faults and newly introduced faults that remain until detection. The function represents the fault-detection rate per remaining fault.
The generalized solution of Equation (3) with the initial conditions and is given by:
where and denotes the time at which the testing process begins.
2.2. Proposed Model
Most existing SRGMs assume that the failures occur independently. However, in practical software systems, failures may exhibit dependent behavior. In these situations, one failure can affect the chances of future failures. To address this issue, this study assumes dependent failures along with an exponentially decaying fault-detection rate. Regarding the exponentially decaying fault-detection rate function, unlike the growth-shaped function, easily detectable faults are found early, and the detection process slows as testing continues.
The mean value function of the proposed model is governed by the following differential equation [15]:
In Equation (4), to reflect the dependent failure behavior, an additional multiplicative term , representing the accumulated failures, is introduced. In Equation (3), failures occur at a rate proportional only to the number of remaining faults which is , implying that failures occur independently. However, in Equation (4), the failure rate is now proportional to both the remaining faults and accumulated failures, expressed as . The inclusion of allows previously occurring failures to influence subsequent failure behavior through cumulative dependency effects. Practically, this formulation can represent failure interactions arising from shared components, interacting modules, or fault propagation effects. Therefore, dependency is introduced through cumulative failure interactions rather than explicit correlation structures or conditional intensity functions.
The generalized solution of Equation (4) is as follows. First, the variables are separated as follows:
When the fault content is assumed to be constant as , which is commonly adopted in software reliability growth modeling, the left-hand side can be decomposed using partial fractions:
Integrating both sides yields the following:
where is integration constant.
Letting and applying the initial conditions , , and , the generalized mean value function is obtained in closed form by Equation (5) as follows:
In this study, the fault-detection rate is represented as a time-dependent function as follows:
where denotes the baseline fault detection rate, represents the initial excess detection rate at the beginning of testing, and is the decay parameter that determines how quickly the fault-detection rate declines over time. During the initial phase of testing, the exponential term is prominent, leading to a higher fault-detection rate because of active testing efforts and a large number of detectable faults. As testing continues, the exponential part diminishes, and slowly approaches the baseline level , indicating the stabilization of the testing process and a decrease in the number of remaining detectable faults. This functional form effectively illustrates the learning effect and decreasing failure-detection behavior that are often observed in real-world software testing scenarios.
Compared with other commonly used fault detection mechanisms, the exponentially decaying function provides a relatively simple and interpretable representation of changing detection behavior. Logistic and S-shaped functions are often used to describe learning effects and delayed growth patterns during testing [3,15]. In contrast, the considered fault detection function assumes that detection efficiency gradually decreases over time while maintaining mathematical simplicity and analytical tractability.
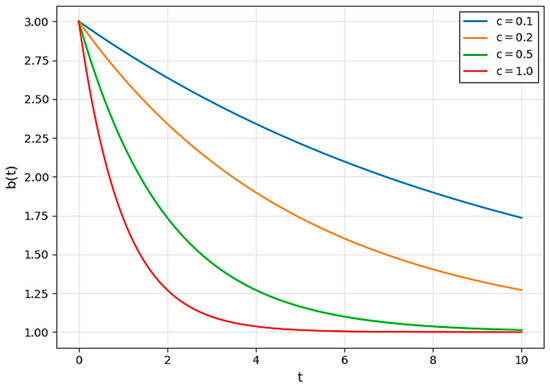
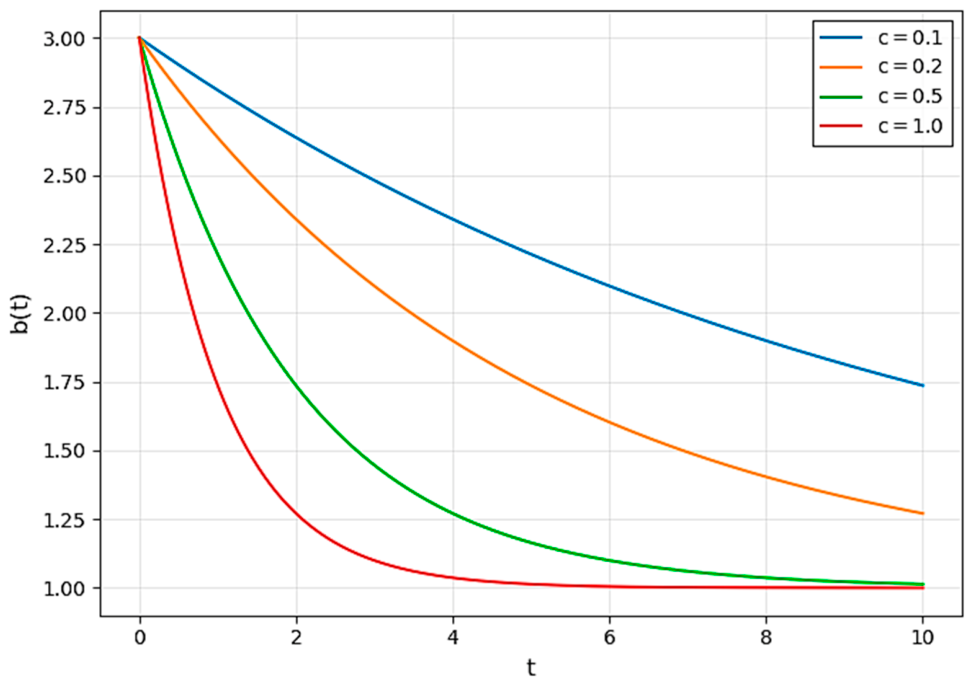
Figure 1 shows how the time-dependent fault-detection rate behaves for different decay parameter values with the other parameters fixed. The fault detection rate begins at the same starting point and steadily decreases with time. The decline rate is greatly affected by the parameter . Specifically, a higher value of results in a quicker decline of , indicating that the ability to detect faults decreases rapidly as the test continues. In contrast, a lower value leads to a slower decline, and the fault-detection process remains stable.
Figure 1.
Time-dependent fault-detection rate for different values of the decay parameter , with and .
Finally, the newly proposed model is expressed by Equation (6) under the initial condition , with a constant fault content and fault-detection rate given by :
Table 1 lists the 18 NHPP-based SRGMs considered in this study. Models 1–15 presume that failures occur independently, whereas the last three models, which include the proposed model, specifically consider the behavior of dependent failures.
Table 1.
Existing and proposed SRGMs.
3. Criteria for Model Evaluation
3.1. Evaluation Criteria
To assess the performance of the proposed model, it was compared to 17 well-known models using 12 performance metrics. This evaluation was based on the difference between the observed values and the estimated mean values . Here, the symbols and denote the number of observations and model parameters, respectively.
Error-based goodness-of-fit measures, such as the mean squared error (MSE), mean absolute error (MAE), and mean error of prediction (MEOP), were calculated by assessing the disparity between the actual and predicted values [26,27].
The explained variance measures and represent the coefficients of determination and adjusted coefficient of determination of the regression equation, respectively [28].
The information theory model selection criteria evaluate model adequacy while accounting for model complexity. Akaike’s information criterion (AIC) and the Bayesian information criterion (BIC) evaluate models by maximizing the likelihood of applying penalties for complexity. AIC is applied to maximize the Kullback–Leibler level between the probability distribution of the model and the data, whereas BIC applies a more significant penalty based on Bayesian model selection principles [29]. Following parameter estimation using the LSE method, the corresponding log-likelihood (logL) values were calculated and subsequently used in the computation of AIC and BIC values. Pham’s information criterion (PIC) and Pham’s criterion (PC) highlight the balance between the fit quality and model simplicity by enforcing stricter penalties on extra parameters, particularly in small-sample situations [30,31].
Predictive performance and stability measures assess the relative deviation and tail behavior of the predictions over time. The predicted relative variation (PRV) measures the dispersion of the prediction bias through its standard deviation [32], whereas the root mean square prediction error (RMSPE) quantifies the overall magnitude of the prediction error [33]. The tail’s statistic (TS) is the average percentage deviation from the mean across all time points [34].
The predicted sum squares error (preSSE) represents the sum of squared differences between the predicted values and the actual values, and it is used to evaluate the prediction accuracy of a model [35].
These 13 criteria were used to evaluate overall model performance. For and adjusted , values closer to one indicate a better model fit, whereas smaller values of the remaining 10 criteria correspond to superior performance. The model parameters were estimated using the least squares estimation (LSE) method, which was executed in MATLAB R2023b and R version 4.4.1, following which all evaluation criteria were calculated. The estimation procedure minimizes the sum of squared errors between the observed cumulative failures and the corresponding values estimated by the model mean value function.
3.2. Multi-Criteria Decision Framework
To further assess the performance of the proposed model, multiple multi-criteria decision metrics such as RED, MCDM, MCDMR, and MCDMM were employed based on the individual evaluation criteria described in Section 3.1. Since different evaluation criteria reflect different aspects of model performance, inconsistencies among individual measures may occur. For example, information criteria such as AIC and BIC consider both fitting accuracy and model complexity, whereas error-based measures evaluate different characteristics of model behavior. Therefore, relying solely on a single criterion may lead to biased conclusions regarding model performance. Multi-criteria decision-making methods have been extensively used in various application domains for ranking and selection problems, including approaches such as AHP, TOPSIS, and fuzzy-based decision frameworks [36,37,38]. However, in software reliability analysis, the use of integrated multi-criteria approaches remains relatively limited.
3.2.1. RED
The RED criterion was used to select the best model based on a set of contributing criteria. The RED function is defined as follows [39]:
where denotes the total number of models, represents the number of evaluation criteria, is the weight associated with the th criterion, denotes the value of criterion for model , and represents the rank of model with respect to criterion . A lower RED value indicates better overall performance, whereas a higher RED value suggests a lower rank compared to the other models.
3.2.2. MCDM
Next, the MCDM was utilized to demonstrate the superiority of the proposed model by conducting a comparative analysis of various SRGMs [40,41]. For this purpose, a decision matrix was constructed, where each element represents the value of a specific evaluation criterion for a given model. The decision matrix is defined as follows Equation (7):
where denotes the total number of models, and represents the number of evaluation criteria. To eliminate scale differences among the criteria, decision matrix was normalized to obtain a normalized matrix . Each element of was calculated as . The normalized matrix is given by Equation (8):
Based on the normalized values, the MCDM values for each model were obtained by summing the normalized criterion values across all the criteria, yielding Equation (9):
3.2.3. MCDMR
The MCDMR reflects the ranking of each suitability among the methods used to determine weights [42]. First, the matrix R was constructed by ranking each model for each criterion using Equation (10):
The ranking of each criterion by was used to create a weight matrix. Matrix was then created by multiplying the normalized matrix defined in Equation (8) by each weight :
The MCDMR value for each model was obtained by summing the values across all criteria, yielding Equation (11):
3.2.4. MCDMM
The MCDMM was introduced to reflect the relative size of each criterion, instead of simply relying on ranking or normalization when computing the MCDM [43]. For this purpose, matrix was constructed to capture the relative size of each criterion. The elements of matrix were calculated by Equation (12) through , where represents the maximum value of criterion among all models:
Next, the matrix was obtained by performing an element-wise product between the matrix defined in Equation (8) and the matrix :
The MCDMM value for each model was obtained by summing the weighted normalized values across all criteria, yielding Equation (13):
In this framework, smaller RED, MCDM, MCDMR, and MCDMM values indicated superior overall performance. To maintain a consistent evaluation across all criteria, the goodness-of-fit measures, and adjusted R2 values, were transformed into and , respectively. The remaining criteria were applied without transformation.
The weighting procedures adopted in the multi-criteria framework are defined as follows. Equal weighting was used for RED and MCDM; that is, all evaluation criteria contribute equally to model assessment. For MCDMR, weights were determined from normalized ranking values. In MCDMM, weight is defined as the ratio between the criterion value and the corresponding maximum criterion value among all models.
4. Numerical Example
4.1. Datasets
Dataset 1 was sourced from the Apache jUDDI project, which is part of the Apache open-source projects and can be accessed via the Apache Issue Tracking System. Failure data were divided into four release groups according to the jUDDI version. Release 1 corresponds to version 3.0.1, followed by Release 2 (version 3.1.0), Release 3 (version 3.1.3), and Release 4 (version 3.1.5) [44]. Dataset 1 was recorded monthly from February 2009 to February 2014, with the total number of failures increasing from an initial count of 10 failures during t = 1, 2, ..., 61 to a cumulative total of 393 failures.
Dataset 2, originally referred to as J3, comprises the failure data gathered during a single phase of subsystem-level integration testing for the Command and Data Subsystem (CDS) associated with project J2. The data was obtained under relatively stable testing conditions, in which the number of testing hours per week and the allocation of testing effort across major functional areas were nearly constant throughout the observation period. Owing to this controlled testing profile, the failure data in J3 were considered more accurate and homogeneous than those of the other projects. During the J3 testing phase, approximately 10.1 faults per thousand lines of code (KLOC) were detected [45]. A cumulative total of 351 failures were recorded weekly over 41 testing periods.
4.2. Results of Dataset 1
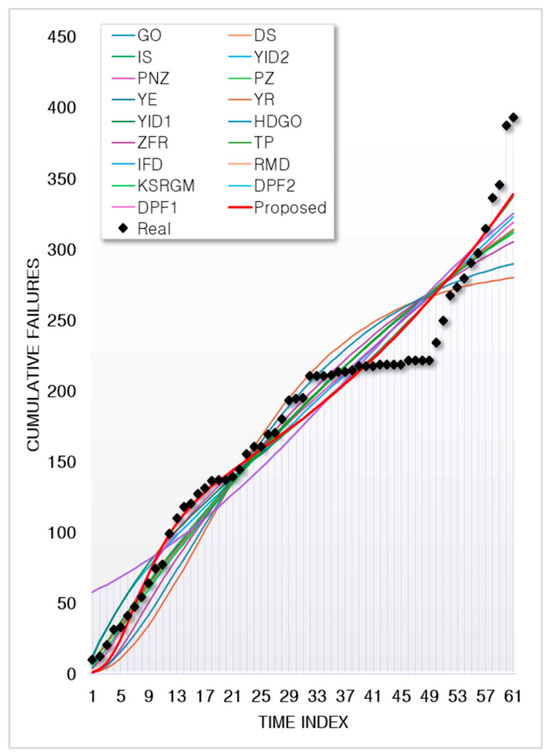
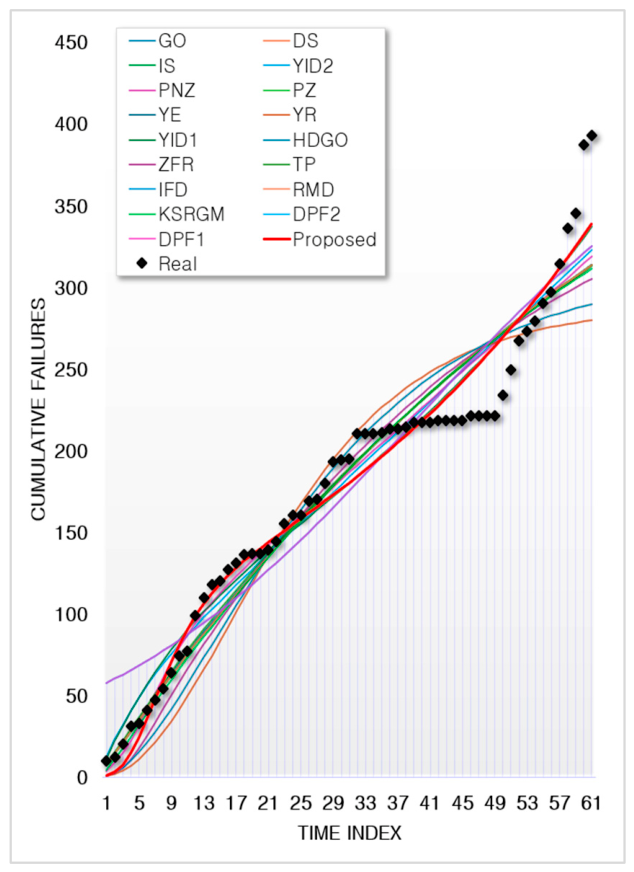
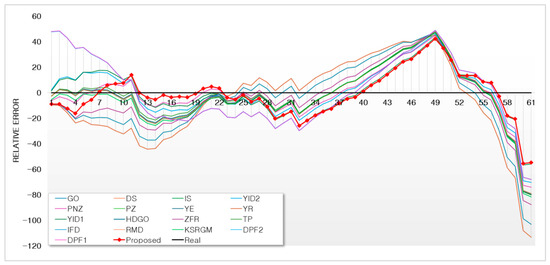
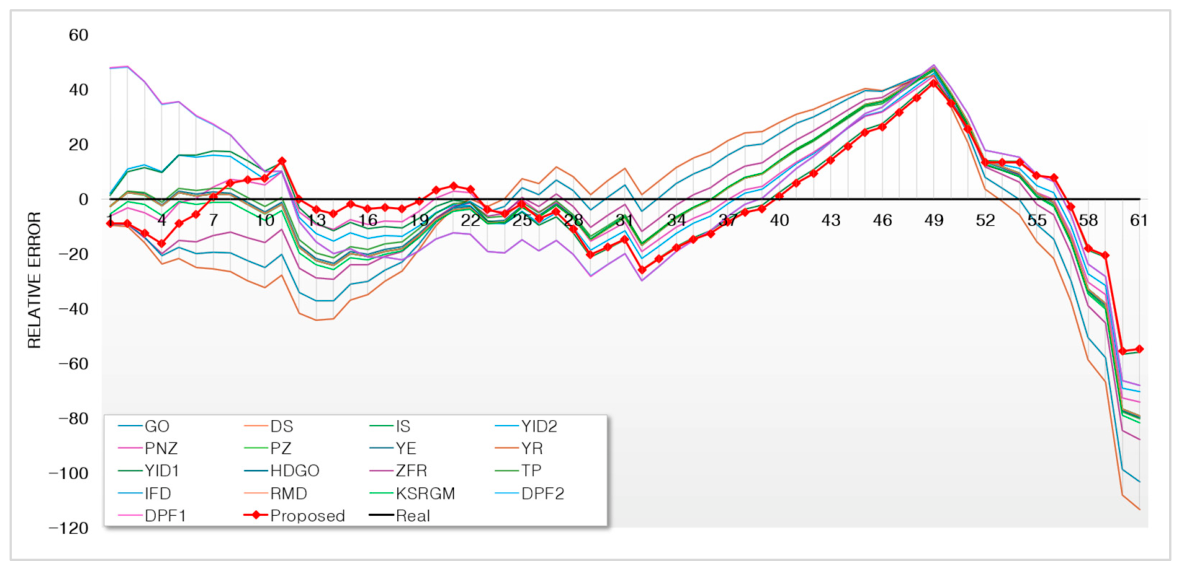
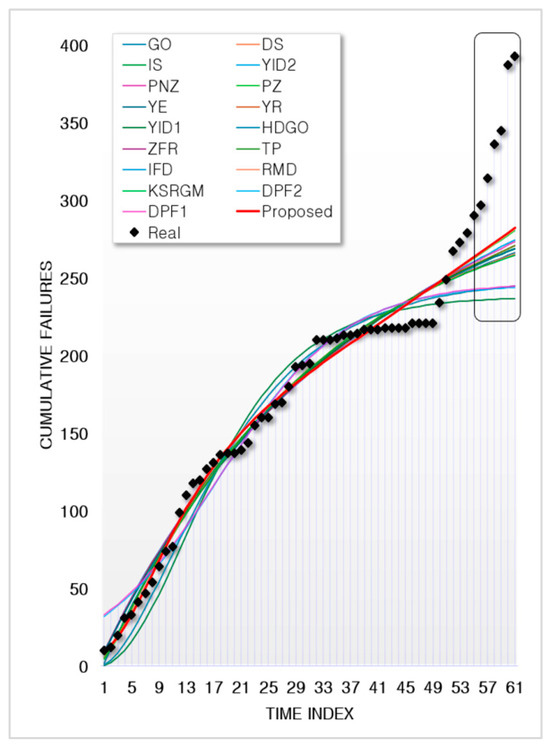
Table 2 lists the estimated parameter values for each model derived from Dataset 1. The proposed model contains five parameters, namely , and . For Dataset 1, the estimated parameter values were , , , , and . Figure 2 shows the actual cumulative number of failures along with the corresponding estimates from all 18 models over the entire period for Dataset 1. The black dots indicate the real cumulative failures, and the red line illustrates the estimates from the proposed model. The other colored lines represent the estimates from the existing comparison models. Figure 3 shows the relative error trajectories for all the models based on Dataset 1, further highlighting the superior estimation accuracy of the proposed model. The model maintained predicted values that were closest to the observed data in comparison with the competing models.
Table 2.
Parameter estimation of all models using Dataset 1.
Figure 2.
Mean value functions of all models using Dataset 1.
Figure 3.
Relative error values of all models using Dataset 1.
Table 3 lists the criteria derived from the estimated parameters listed in Table 2. It is evident that the MSE, PRV, RMSPE, MAE, MEOP, TS, PIC, and PC values for the proposed model were the lowest at 353.2984, 18.1330, 18.1585, 14.3778, 14.1255, 8.9496, 19,859.7117, and 167.2473, respectively. Furthermore, the R2 and adjusted R2 values were the highest, with values of 0.9597 and 0.9560, respectively, and were the closest to one among all models. Regarding the AIC and BIC criteria, although they do not represent the lowest values, they ranked second among all models with values of 616.3507 and 626.9051, respectively. The YID1 model exhibited the lowest AIC and BIC values (598.8362 and 605.1689, respectively).
Table 3.
Comparison of the criteria of all models using Dataset 1.
The 95% confidence intervals for the datasets were computed as follows:
where is defined as the th percentile of the standard normal distribution [5].
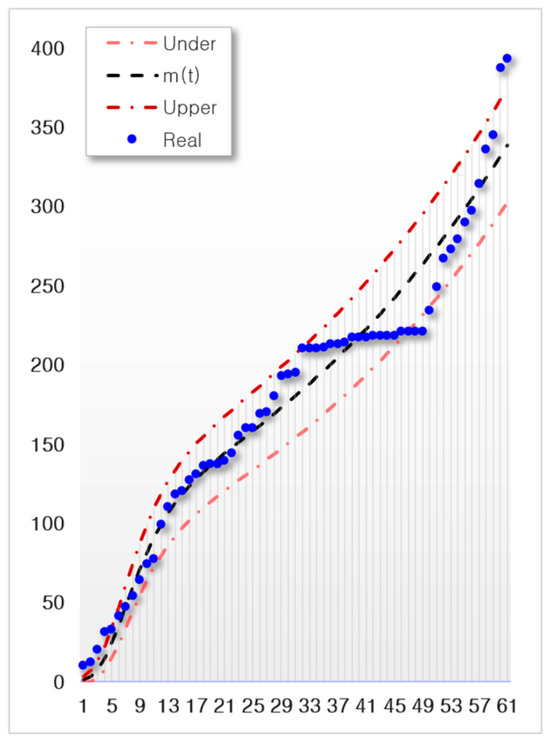
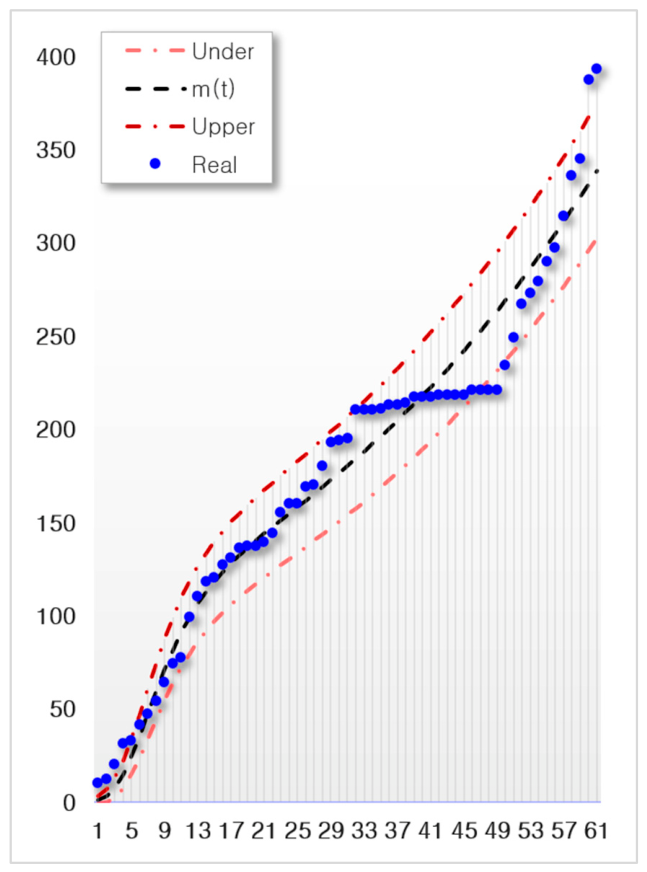
Figure 4 shows the 95% confidence interval for Dataset 1. The proposed model provided a good fit during the early and middle testing phases. However, deviations were observed in the later period when several observations fell outside the estimated 95% confidence interval. The deviations observed in the later testing phase indicate the possible presence of structural changes in the failure detection process. In future studies, incorporating change-point detection methods into the proposed NHPP framework will enable the model to adapt to regime shifts by partitioning the testing period into multiple phases with distinct parameter values. Such an extension is expected to further improve model flexibility and predictive accuracy, particularly in long-term or dynamically evolving software systems.
Figure 4.
95% confidence intervals of the proposed model using Dataset 1.
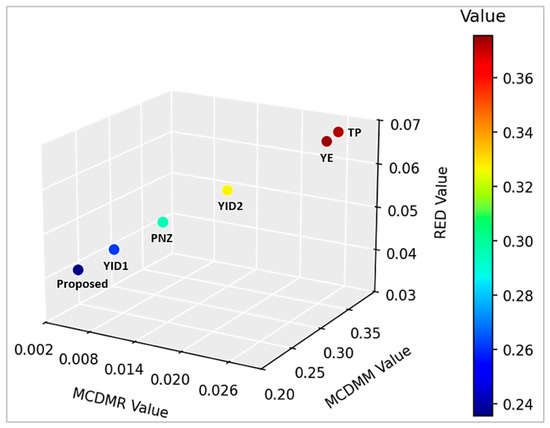
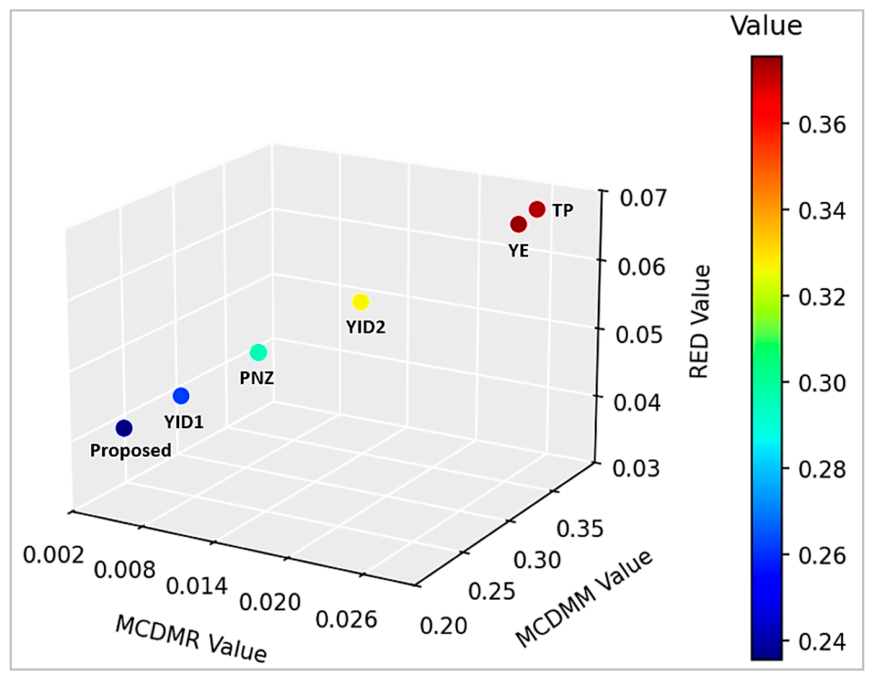
Table 4 lists the results of the multi-criteria calculations based on the values reported in Table 3. The proposed model achieved superior overall performance across all multi-criteria metrics, with RED = 0.0396, MCDM = 0.4675, MCDMR = 0.0033, and MCDMM = 0.2345. These findings indicate that the proposed model consistently surpassed all the models included in the study. To enhance visual comprehension, Figure 5 presents a three-dimensional plot of RED, MCDMR, and MCDMM for the top six of the 18 models assessed using Dataset 1. The RED metric is shown in place of MCDM because both MCDMR and MCDMM originate from the MCDM metric. Thus, RED serves as an independent and supplementary metric for comparative visualization.
Table 4.
Comparison of multi-criteria calculations of all models using Dataset 1.
Figure 5.
3D plot of MCDMR, MCDMM, and RED of models using Dataset 1.
4.3. Results of Dataset 2
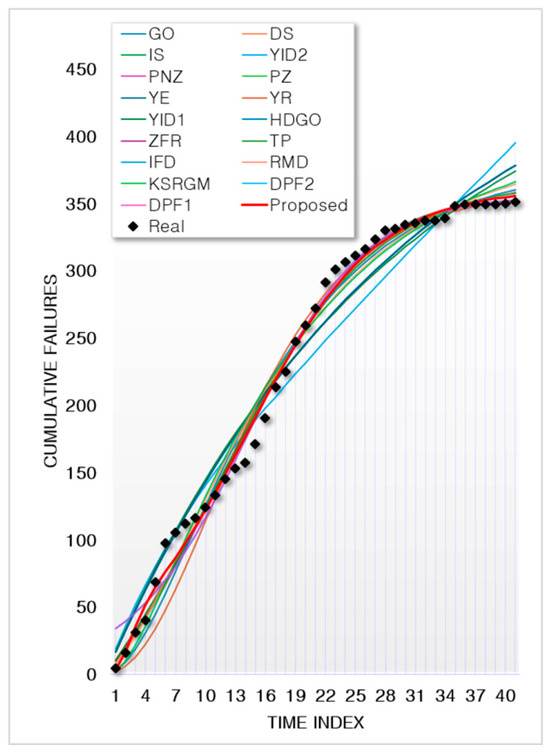
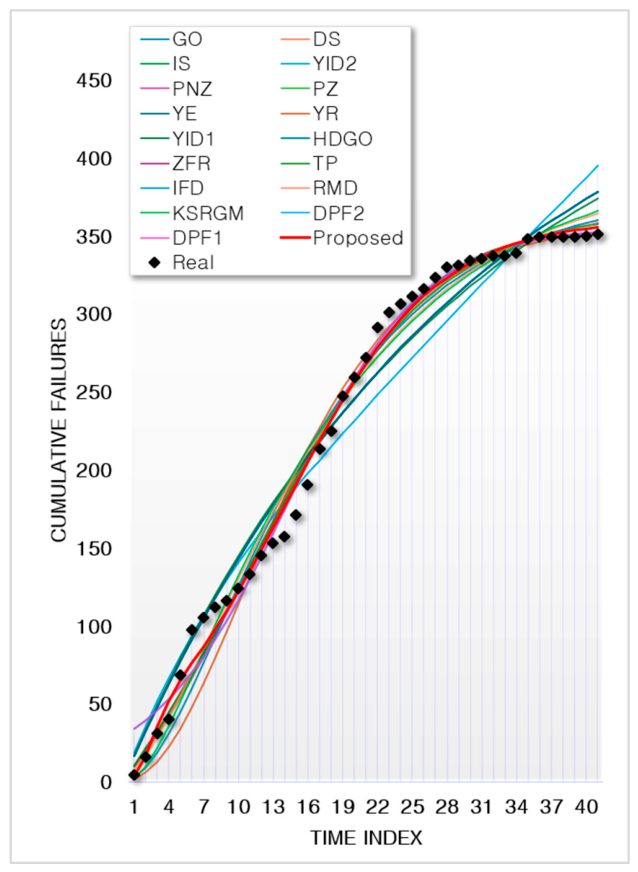
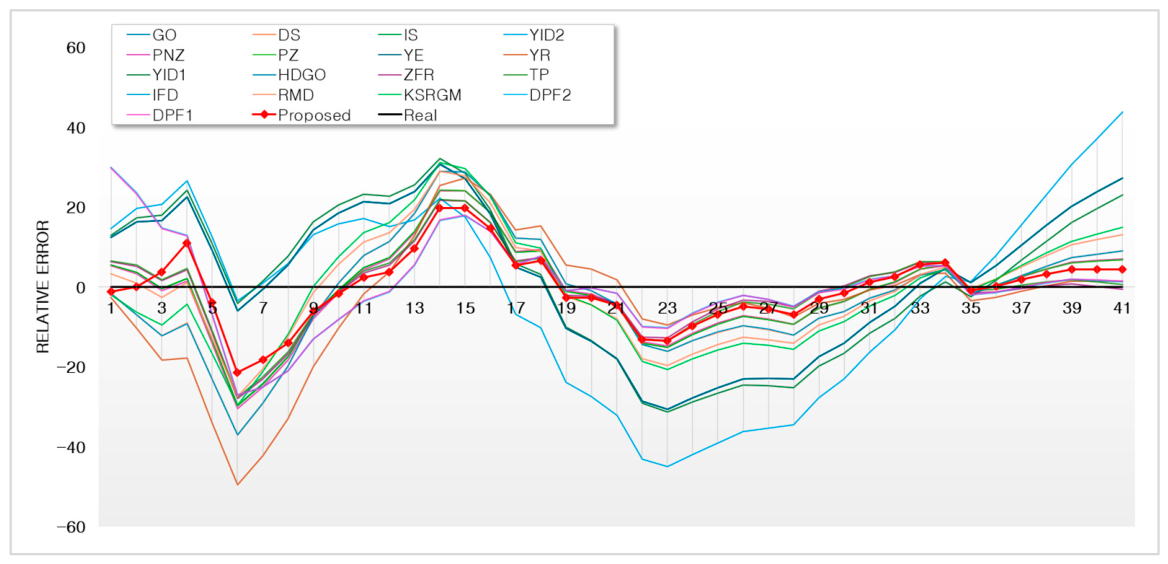
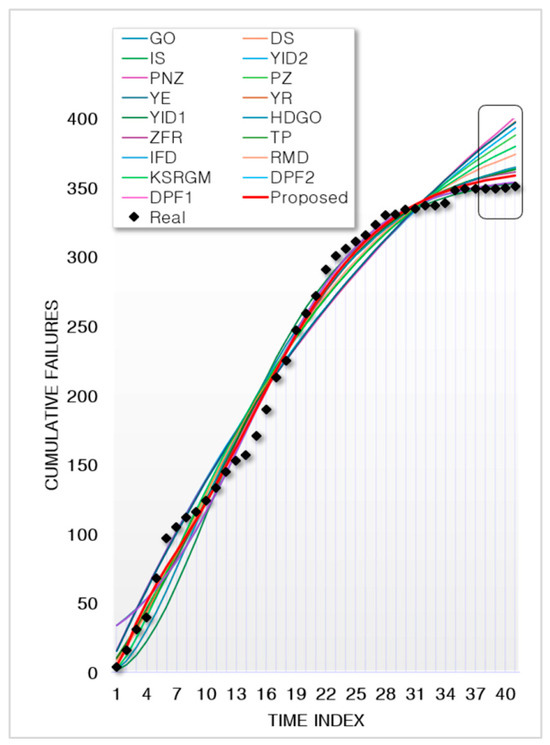
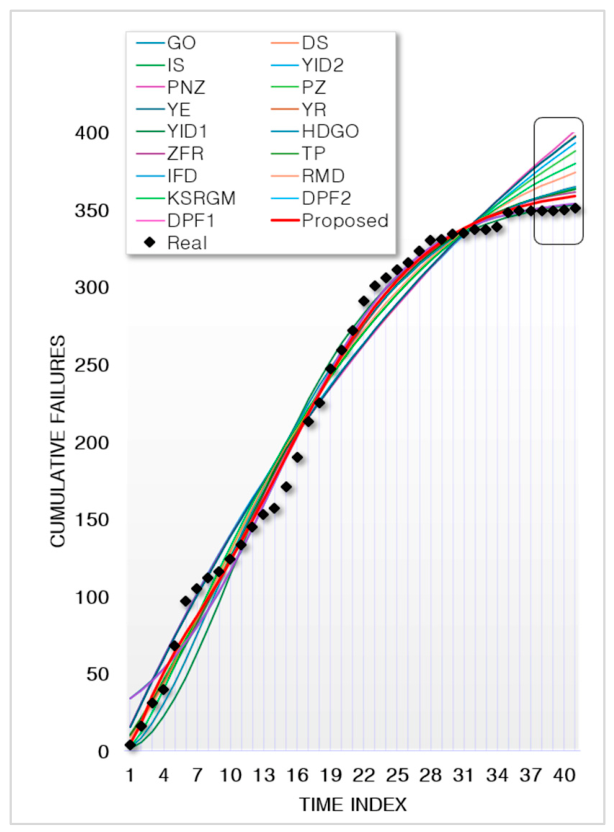
Table 5 lists the estimated parameter values for each model obtained using Dataset 2. The proposed model contains five parameters: and . Each parameter in the proposed model was estimated as follows: , , , and . Figure 6 shows the real cumulative number of failures, along with the corresponding estimates from all 18 models for Dataset 2. The black dots represent the real cumulative failures and the red line represents the estimates from the proposed model. The other colored lines indicate the estimates from existing comparison models. Figure 7 presents the relative error trajectories for all models based on Dataset 2, which shows the predicted values closest to the observed data compared to the other models.
Table 5.
Parameter estimations of all models using Dataset 2.
Figure 6.
Mean value functions of all models using Dataset 2.
Figure 7.
Relative error values of all models using Dataset 2.
Table 6 lists the criteria derived from the estimated parameters listed in Table 5. It is evident that the values of MSE, AIC, BIC, PRV, RMSPE, MAE, MEOP, TS, PIC, and PC for the proposed model were the lowest, with values of 87.4928, 269.7000, 278.2678, 8.8697, 8.8737, 7.5787, 7.3739, 3.3982, 3199.7414, and 83.7026, respectively. Moreover, the R2 and adjusted R2 values were the highest, with values of 0.9939 and 0.9931, respectively, which were the closest to one among all models. This outcome indicates that the proposed model demonstrated superior performance in fitting Dataset 2.
Table 6.
Comparison of criteria of all models using Dataset 2.
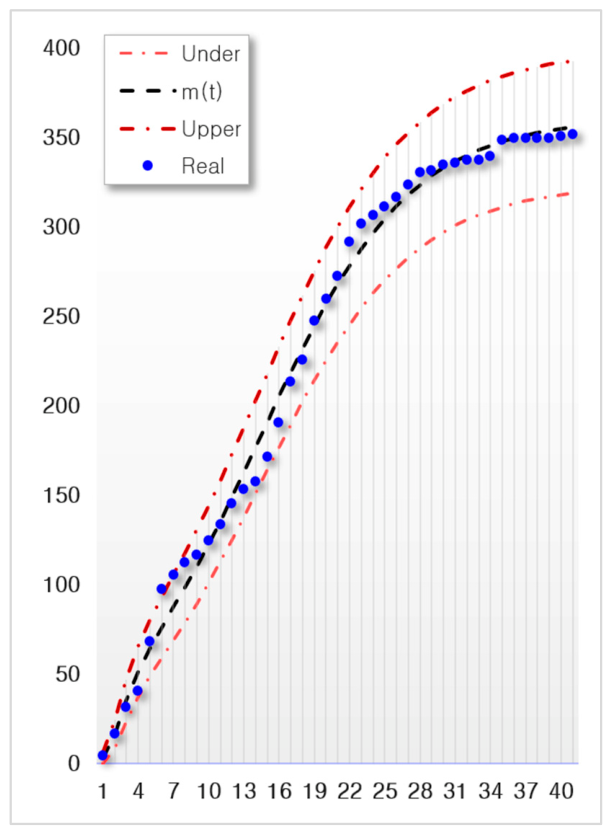
Figure 8 shows the estimated mean value function and its corresponding 95% confidence interval. The proposed model accurately captured the overall failure trends. In the early stages, nearly all actual failures were within the confidence interval, except at two time points (in the 1st and 6th week). Given the stochastic nature of the NHPP-based failure process, such occasional deviations were expected and did not undermine the overall adequacy of the model fit.
Figure 8.
95% confidence intervals of the proposed model using Dataset 2.
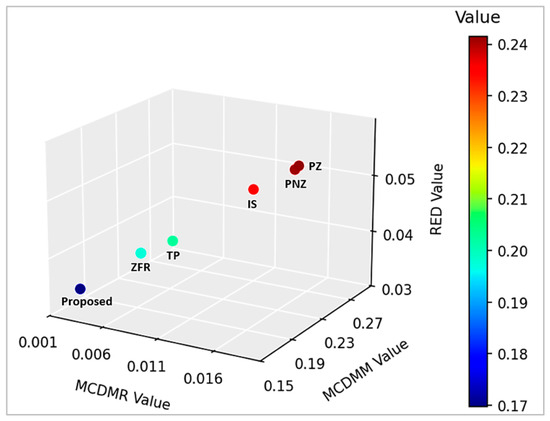
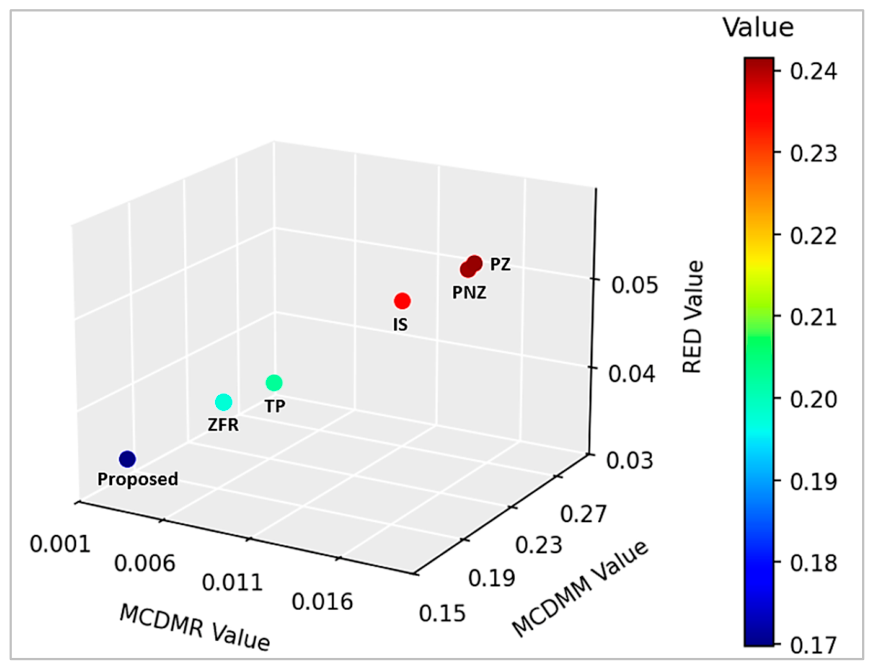
Table 7 lists the results of the multi-criteria evaluation calculated based on the values reported in Table 6. Similar to Dataset 1, the proposed model achieved superior overall performance across all multi-criteria metrics, with RED = 0.0336, MCDM = 0.3963, MCDMR = 0.0023, and MCDMM = 0.1697. Figure 9 presents a three-dimensional plot of RED, MCDMR, and MCDMM for the top six models among the 18 models assessed using Dataset 2. The top-performing models for Dataset 2 included the proposed model, ZFR, TP, IS, PZ, and PNZ, which differ from the top six models identified for Dataset 1 (the proposed model, YID1, YID2, YE, PNZ, and TP).
Table 7.
Comparison of multi-criteria calculations of all models using Dataset 2.
Figure 9.
3D plot of MCDMR, MCDMM, and RED of models using Dataset 2.
4.4. Sensitivity Analysis
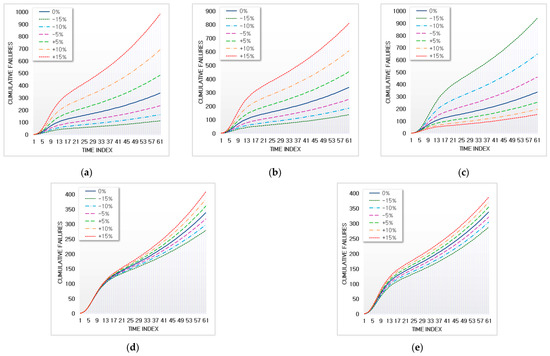
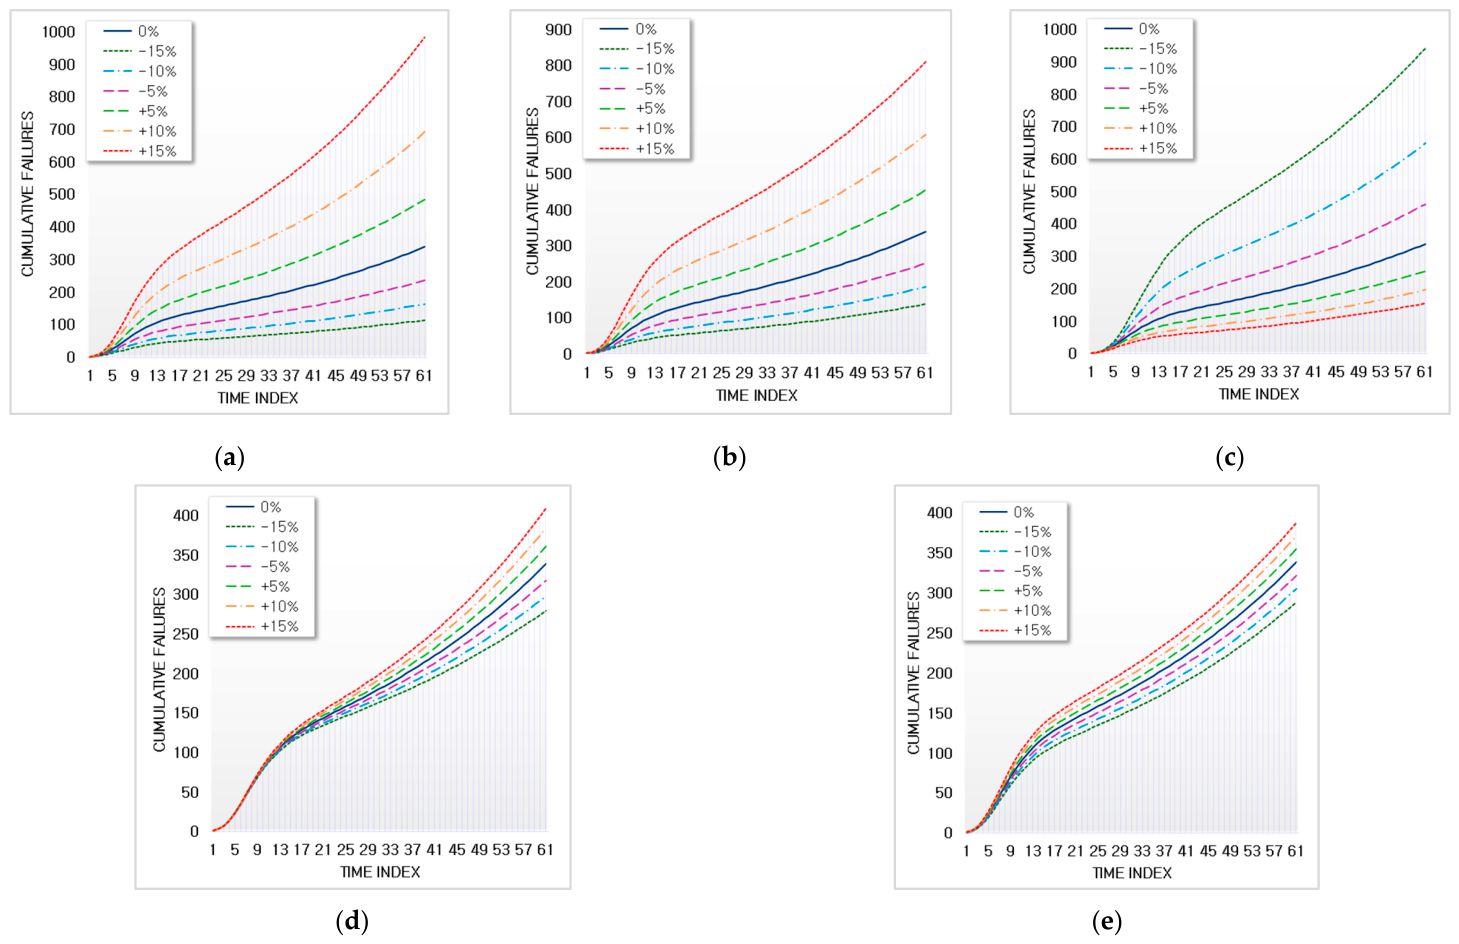
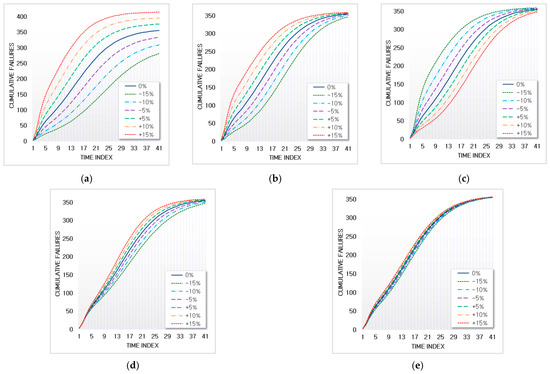
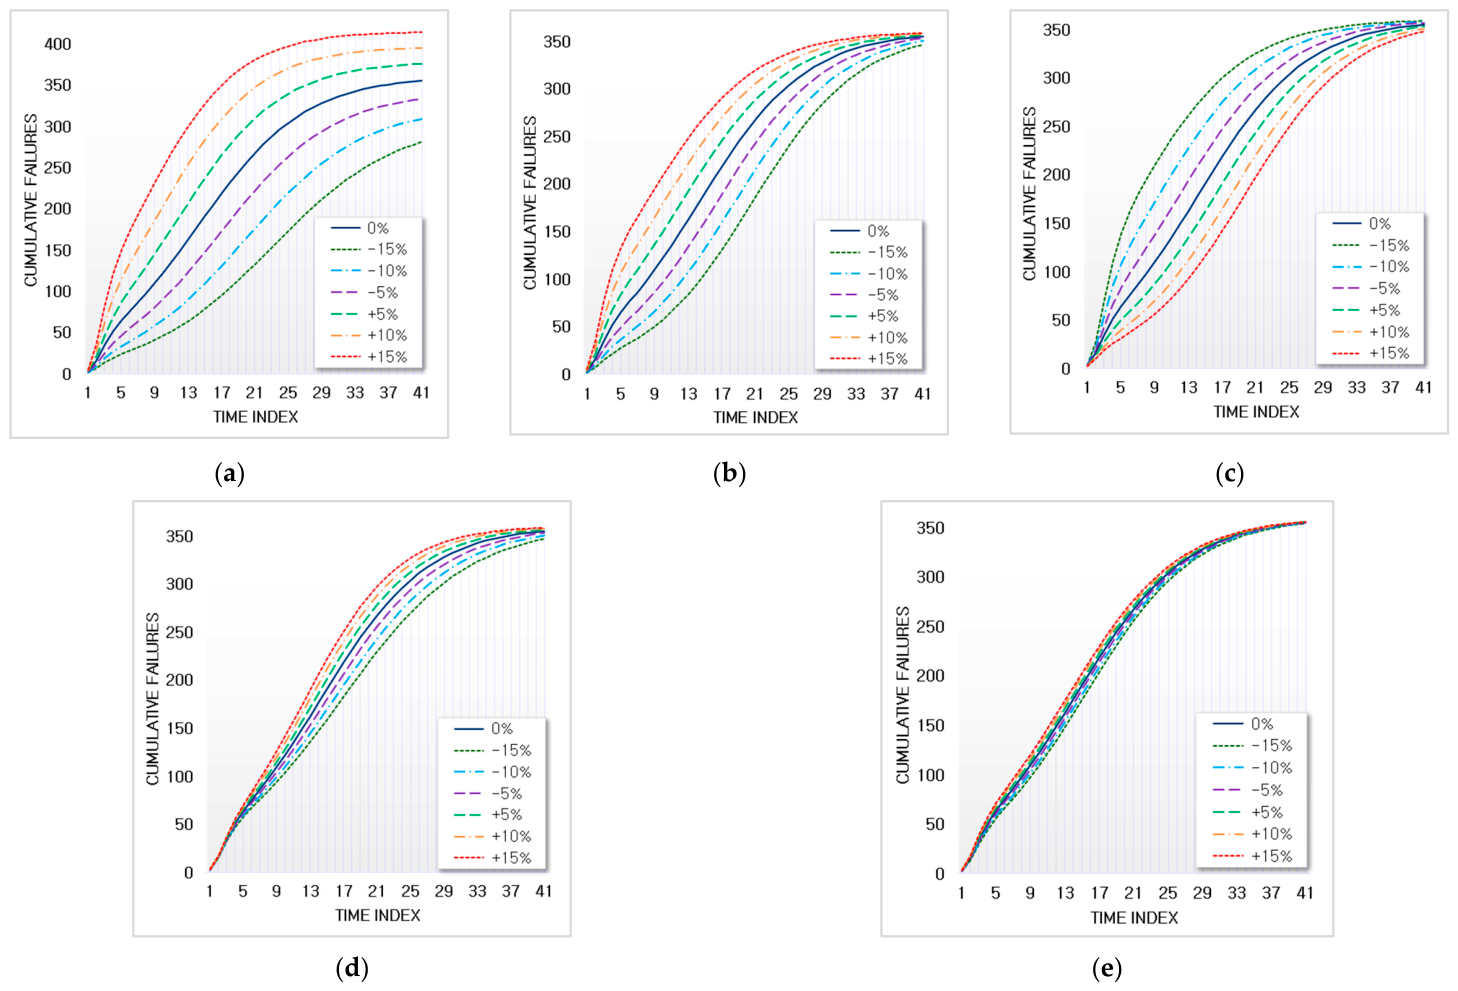
To examine the effect of the parameters on the behavior of the proposed model, a one-at-a-time sensitivity analysis was conducted. This analysis helped identify the significance of the model parameters and assess the robustness of the proposed model to parameter variations [46,47]. In this analysis, with other parameters held constant, the parameter was adjusted by , , and around the estimate. The resulting graphs for the two datasets are shown in Figure 10 and Figure 11.
Figure 10.
Sensitivity analysis of changes in the parameters for Dataset 1. (a) parameter , (b) parameter , (c) parameter , (d) parameter , and (e) parameter .
Figure 11.
Sensitivity analysis of changes in the parameters for Dataset 2. (a) parameter , (b) parameter , (c) parameter , (d) parameter , and (e) parameter .
For Dataset 1, the results indicate that the proposed model shows different sensitivity levels across parameters. Parameters , , and show relatively high sensitivity, whereas and exhibit comparatively lower sensitivity. Higher values of parameters and result in higher cumulative failures, indicating that these parameters positively influence the fault growth process. In contrast, parameter exhibits a reversed sensitivity pattern: increasing this parameter decreases the cumulative failures, whereas decreasing increases it. Thus, demonstrating a negative relationship with the growth behavior of the model. On the other hand, the relatively smaller deviations observed for and indicate that the proposed model is less sensitive to changes in these parameters and therefore maintains stable behavior under moderate change.
Compared with Dataset 1, Dataset 2 results show noticeably smaller separations among the sensitivity curves, particularly for parameters and . This indicates that the cumulative failure predictions in Dataset 2 are less affected by parameter perturbations and therefore exhibit greater robustness and stability. In Dataset 1, parameter variations produce larger deviations throughout the testing process, especially in the later stages, implying stronger dependence of model predictions on parameter estimation accuracy. In contrast, the curves in Dataset 2 tend to converge toward similar final cumulative failures, suggesting that the model is more constrained and less sensitive to moderate parameter changes. Overall, these results imply that although , , and remain dominant parameters in both datasets, the proposed model displays more stable predictive behavior for Dataset 2 than for Dataset 1.
The observed differences in sensitivity behavior between the two datasets may be attributed to their distinct software development and failure generation characteristics. Dataset 1 corresponds to an open-source software environment collected over a longer period and may involve iterative development, repeated updates, and evolving software conditions, which can introduce more variable failure patterns and stronger parameter interactions. Therefore, changes in parameter values can propagate more strongly throughout the testing process, leading to larger deviations in cumulative failure behavior. In contrast, Dataset 2 represents a closed-type industrial software environment collected during a relatively controlled testing phase, where the failure process appears more stable and structured. As a result, parameter perturbations have comparatively smaller effects on cumulative failures, producing more robust and consistent model behavior. These findings suggest that the characteristics of the underlying software environment can influence the sensitivity and stability of model parameters.
4.5. Prediction Analysis
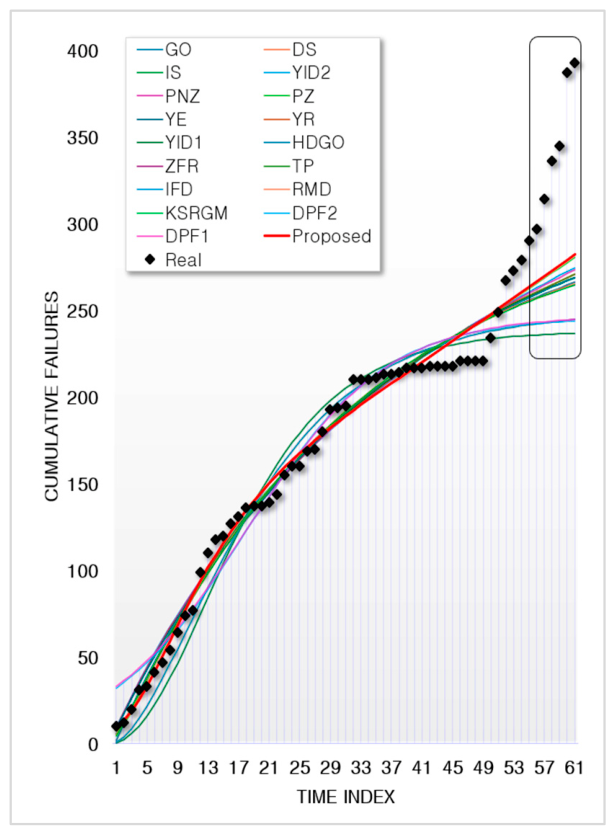
To further evaluate the predictive capability of the proposed model, a prediction analysis was performed by estimating model parameters using 90% of the dataset and predicting the remaining 10%. Table 8 shows that the estimated parameter values obtained using 90% of Dataset 1 differ substantially in magnitude from 100% estimation. Proposed model’s parameter decreases from 12,867.0328 to 610.8339, while increases from 0.2144 to 5.7205, with noticeable variations also observed in other parameters. However, such differences do not necessarily imply instability in the proposed model. Since the model is nonlinear and contains multiple interacting parameters, different parameter combinations can generate similar cumulative failures. When only 90% of the data are used for estimation, the fitting process is primarily influenced by the earlier and middle stages of the failure process and excludes the final 10% of data. Therefore, the model compensates for the missing information of later stages of data by adjusting parameter values to preserve the overall growth behavior. This results in substantial variations in individual parameter estimates even though the overall failure trajectories remain relatively consistent. From Figure 12 and Figure 13, the results indicate that the proposed model provides a satisfactory fit during the training phase while maintaining reasonable predictive performance in the testing phase. In the prediction part, the real cumulative failures show a noticeable increase following a relatively stable period. The proposed model is able to follow this increasing trend more effectively than several existing models, many of which tend to underestimate the later-stage growth and produce comparatively flatter prediction curves.
Table 8.
The estimated parameter values of the model using 90% of Dataset 1.
Figure 12.
Estimated values for the training data and predicted values for the 10% of Dataset 1. The gray box denotes the 10% prediction region.
Figure 13.
Estimated values for the training data and predicted values for the 10% of Dataset 2. The gray box denotes the 10% prediction region.
Table 9 presents the comparison of goodness-of-fit criteria and preSSE values for models using 90 of Dataset 1. The results indicate that the proposed model demonstrates superior overall performance across most evaluation measures. The proposed model achieves the smallest values for AIC, BIC, PRV, RMSPE, TS, PIC, PC, and preSSE, while also attaining the highest R2 value among all comparing models. For MSE, MAE, and MEOP, the model provides the second-smallest values, slightly behind PNZ model. Although the PNZ model exhibits marginally better performance in these error-based criteria, the proposed model performs better across broader range of criteria and provides smallest preSSE value, indicating stronger predictive capability for unseen data. Furthermore, to provide a more comprehensive assessment of model performance and reduce potential bias associated with relying on individual criteria, multi-criteria decision-making approaches were also employed. Results can be seen in Table 10. The proposed model achieved the best overall performance under all methods, including RED, MCDM, MCDMR, and MCDMM. These results further support the robustness and stability of the proposed model by demonstrating that its superior performance is consistently maintained even when preSSE is included.
Table 9.
The comparison of goodness-of-fit criteria and preSSE for models using 90% of Dataset 1.
Table 10.
Comparison of multi-criteria calculations of all models using 90% of Dataset 1.
It is noteworthy that when the complete Dataset 1 was used, the proposed model achieved only the second-smallest values for AIC and BIC. This can be attributed to the penalty components of AIC and BIC, which evaluate both fitting accuracy and model complexity. Due to the nonlinear structure and parameter interactions within the proposed model, a slightly larger complexity penalty may be imposed compared with other models. However, the prediction results based on 90% of data show superior results across multiple criteria. These suggest that proposed model exhibits stronger predictive capability and better generalization performance.
Compared with Dataset 1, Table 11 shows that only relatively small changes are observed across the estimated parameters for Dataset 2. This suggests that the estimation process for Dataset 2 is less sensitive to the exclusion of the final 10% of data. Unlike Dataset 1, where substantial parameter adjustments occurred to compensate for missing information, Dataset 2 exhibits greater parameter stability and consistency.
Table 11.
The estimated parameter values of the model using 90% of Dataset 2.
Table 12 results indicate that the proposed model achieves superior overall performance, producing the best results for all twelve goodness-of-fit criteria among the compared models. This demonstrates that the proposed model effectively captures the overall software failure growth process and provides a highly accurate representation of the observed data during the training stage. However, despite its good fitting performance, the proposed model achieves only the fifth-smallest preSSE value in the prediction analysis. Since the preSSE evaluates prediction performance only on the remaining 10% of data, it is highly sensitive to the characteristics of the final testing stage rather than reflecting the model’s overall fitting capability. The later part of Dataset 2 exhibits a nearly saturated growth behavior with only minor changes in cumulative failures. Therefore, models capable of producing stronger flattening behavior in the tail region naturally obtain lower preSSE values. Models that show good results in preSSE, such as YR, PZ, DPF1, and DPF2 incorporate additional structural characteristics like delayed S-shaped behavior, logistic fault detection mechanisms, evolving fault content and dependent failure effects. These mechanisms provide additional flexibility in controlling the asymptotic behavior and adjusting curvature of the reliability growth process during the late testing stage.
Table 12.
The comparison of goodness-of-fit criteria and preSSE for models using 90% of Dataset 2.
In contrast, the proposed model’s fault content remains constant, and the fault detection rate gradually approaches a nonzero constant value as testing progresses. Although this structure effectively achieves excellent fitting performance, it is primarily designed to represent the complete reliability growth behavior rather than specifically adapting to nearly stationary growth patterns within a limited prediction region.
Lastly, despite achieving only fifth-smallest preSSE value, the proposed model consistently obtained the best overall ranking under the RED, MCDM, MCDMR and MCDMM approaches (Table 13). Since these methods simultaneously consider multiple goodness-of-fit and prediction criteria, the results suggest that the relatively larger preSSE value has limited influence on the overall evaluation. This indicates that the proposed model maintains superior balance among fitting accuracy, prediction behavior, and reliability growth representation compared with other models.
Table 13.
Comparison of multi-criteria calculations of all models using 90% of Dataset 2.
5. Conclusions
This study proposed a new NHPP-based SRGM that explicitly accounts for dependent failure behavior with an exponentially decaying fault-detection rate, addressing a key limitation of many classical SRGMs that rely on the assumption of independent failures. By incorporating the failure dependency into the modeling framework, the proposed model accurately reflects realistic software testing and debugging environments characterized by fault interactions, shared components, and imperfect debugging processes. To provide a comprehensive and balanced evaluation of the competing models, this study adopted an integrated multi-criteria decision-making method that incorporates MCDM, MCDMR, MCDMM, and RED. Unlike conventional single-criterion approaches, this framework enables simultaneous consideration of multiple performance and stability criteria.
The effectiveness of the proposed approach was demonstrated through extensive analysis using both closed-type industrial software and OSS failure datasets. Across all evaluated datasets, the proposed model consistently achieved superior performance under all multi-criteria metrics, confirming its robustness. The results indicate that explicitly modeling dependent failures combined with a multi-criteria evaluation strategy leads to more reliable and informative assessments of software reliability growth. In particular, the prediction analysis further demonstrated that the proposed model preserves the overall software failure growth pattern and maintains satisfactory predictive capability even under reduced training conditions. Although prediction performance varied depending on dataset characteristics, the proposed model consistently exhibited good generalization ability. Furthermore, sensitivity analysis revealed that the effects of parameter variations differ across datasets and parameters. Parameters related to fault content and fault detection showed stronger influence on cumulative failure behavior, while other parameters exhibited relatively lower sensitivity.
From a practical perspective, the proposed model can assist software testing managers in estimating software reliability growth and monitoring failure trends during the testing process. The predicted reliability information may support more informed release planning decisions, help identify appropriate testing durations, and assist in allocating testing resources more effectively according to software quality requirements.
Limitations of this study should also be acknowledged. First, parameter estimation was performed using the LSE approach without comparison to alternative estimation methods such as MLE or Bayesian approaches. Second, uncertainty quantification was based on approximate confidence interval estimation rather than more advanced approaches such as bootstrap or likelihood methods. Finally, the multi-criteria framework employed RED, MCDM, MCDMR, and MCDMM methods, while comparisons with alternative decision-making approaches such as AHP and TOPSIS were beyond the scope of the present study.
Future research may extend the proposed model by incorporating change-point mechanisms to capture the structural shifts in software reliability growth caused by changes in testing strategies or operational environments. In addition, the multi-criteria decision method can be further extended by developing a new mean-based MCDM approach capable of handling interval data. This method would enable a more robust model comparison by simultaneously accounting for the performance variability, uncertainty, and robustness.
Author Contributions
Conceptualization, I.H.C. and K.Y.S.; methodology, I.H.C.; software, O.-U.O.; validation, I.H.C. and K.Y.S.; formal analysis, K.Y.S. and O.-U.O.; data curation, O.-U.O.; writing—original draft preparation, K.Y.S. and O.-U.O.; writing—review and editing, K.Y.S. and I.H.C.; visualization, O.-U.O.; supervision, I.H.C.; funding acquisition, K.Y.S. All authors have read and agreed to the published version of the manuscript.
Funding
This study was supported by research fund from Chosun University, 2026.
Data Availability Statement
The data presented in this study are available in the Apache Issue Tracking System for the Apache jUDDI project and in the published source for the J3/CDS software reliability dataset, cited as References [44,45], respectively. These data were derived from the following resources available in the public domain: the Apache jUDDI project and the J3/CDS software reliability dataset.
Acknowledgments
The authors would like to thank Chosun University for its research support in 2026.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Goel, A.L.; Okumoto, K. Time-Dependent Error-Detection Rate Model for Software Reliability and Other Performance Measures. IEEE Trans. Reliab. 1979, R-28, 206–211. [Google Scholar] [CrossRef] [Scilit]
- Yamada, S. Software Reliability Modeling: Fundamentals and Applications; Springer: Tokyo, Japan, 2014. [Google Scholar] [CrossRef]
- Yamada, S.; Ohba, M.; Osaki, S. S-Shaped Reliability Growth Modeling for Software Error Detection. IEEE Trans. Reliab. 1983, R-32, 475–484. [Google Scholar] [CrossRef] [Scilit]
- Haque, A.; Ahmad, N. Key Issues in Software Reliability Growth Models. Recent Adv. Comput. Sci. Commun. 2022, 15, 741–747. [Google Scholar] [CrossRef] [Scilit]
- Pham, H. System Software Reliability; Springer: London, UK, 2006. [Google Scholar] [CrossRef] [Scilit]
- Yamada, S.; Osaki, S. Software Reliability Growth Modeling: Models and Applications. IEEE Trans. Softw. Eng. 1985, SE-11, 1431–1437. [Google Scholar] [CrossRef] [Scilit]
- Pham, H.; Nordmann, L.; Zhang, Z. A general imperfect-software-debugging model with S-shaped fault-detection rate. IEEE Trans. Reliab. 1999, 48, 169–175. [Google Scholar] [CrossRef] [Scilit]
- Su, C.; Wang, J.; Wang, X.; Li, Z. Robustness analysis of clustered mine cyber-physical system considering node overload and underload under cascading failure. Proc. Inst. Mech. Eng. Part O J. Risk Reliab. 2026. [Google Scholar] [CrossRef] [Scilit]
- Pham, H.; Zhang, X. An NHPP Software Reliability Model and Its Comparison. Int. J. Reliab. Qual. Saf. Eng. 1997, 4, 269–282. [Google Scholar] [CrossRef] [Scilit]
- Pham, H.; Zhang, X. NHPP software reliability and cost models with testing coverage. Eur. J. Oper. Res. 2003, 145, 443–454. [Google Scholar] [CrossRef] [Scilit]
- Wang, J.; Geng, H.; Li, P. A software reliability model for open source big data systems based on Weibull–Weibull distribution. Sci. Rep. 2025, 15, 14670. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wang, J.; Li, P.; Hu, J.; Ce, Z. A multi-release reliability model of open source software with fault detection obeying three-parameter lifetime distribution. Sci. Rep. 2024, 14, 19576. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Hwang, C.L.; Yoon, K. Multiple Attribute Decision Making; Springer: Berlin/Heidelberg, Germany, 1981. [Google Scholar] [CrossRef] [Scilit]
- Opricovic, S.; Tzeng, G.-H. Compromise solution by MCDM methods: A comparative analysis of VIKOR and TOPSIS. Eur. J. Oper. Res. 2004, 156, 445–455. [Google Scholar] [CrossRef] [Scilit]
- Lee, D.H.; Chang, I.H.; Pham, H. Software Reliability Model with Dependent Failures and SPRT. Mathematics 2020, 8, 1366. [Google Scholar] [CrossRef] [Scilit]
- Yamada, S.; Ohba, M.; Osaki, S. s-Shaped Software Reliability Growth Models and Their Applications. IEEE Trans. Reliab. 1984, R-33, 289–292. [Google Scholar] [CrossRef] [Scilit]
- Ohba, M. Software reliability analysis models. IBM J. Res. Dev. 1984, 28, 428–443. [Google Scholar] [CrossRef] [Scilit]
- Yamada, S.; Tokuno, K.; Osaki, S. Imperfect debugging models with fault introduction rate for software reliability assessment. Int. J. Syst. Sci. 1992, 23, 2241–2252. [Google Scholar] [CrossRef] [Scilit]
- Yamada, S.; Ohtera, H.; Narihisa, H. Software Reliability Growth Models with Testing-Effort. IEEE Trans. Reliab. 1986, 35, 19–23. [Google Scholar] [CrossRef] [Scilit]
- Hossain, S.A.; Dahiya, R.C. Estimating the parameters of a non-homogeneous Poisson-process model for software reliability. IEEE Trans. Reliab. 1993, 42, 604–612. [Google Scholar] [CrossRef] [Scilit]
- Zhang, X.; Teng, X.; Pham, H. Considering fault removal efficiency in software reliability assessment. IEEE Trans. Syst. Man Cybern.-Part A Syst. Hum. 2003, 33, 114–120. [Google Scholar] [CrossRef] [Scilit]
- Teng, X.; Pham, A. A New Methodology for Predicting Software Reliability in the Random Field Environments. Reliab. IEEE Trans. 2006, 55, 458–468. [Google Scholar] [CrossRef]
- Roy, P.; Mahapatra, D.G.S.; Dey, K. An NHPP software reliability growth model with imperfect debugging and error generation. Int. J. Reliab. Qual. Saf. Eng. 2014, 21, 1450008. [Google Scholar] [CrossRef] [Scilit]
- Kapur, P.K.; Pham, H.; Anand, S.; Yadav, K. A Unified Approach for Developing Software Reliability Growth Models in the Presence of Imperfect Debugging and Error Generation. IEEE Trans. Reliab. 2011, 60, 331–340. [Google Scholar] [CrossRef] [Scilit]
- Kim, Y.S.; Song, K.Y.; Pham, H.; Chang, I.H. A Software Reliability Model with Dependent Failure and Optimal Release Time. Symmetry 2022, 14, 343. [Google Scholar] [CrossRef] [Scilit]
- Armstrong, J.S.; Collopy, F. Error measures for generalizing about forecasting methods: Empirical comparisons. Int. J. Forecast. 1992, 8, 69–80. [Google Scholar] [CrossRef] [Scilit]
- Willmott, C.J.; Matsuura, K. Advantages of the mean absolute error (MAE) over the root mean square error (RMSE) in assessing average model performance. Clim. Res. 2005, 30, 79–82. [Google Scholar] [CrossRef] [Scilit]
- Akossou, A.Y.J.; Palm, R. Impact of data structure on the estimators R-square and adjusted R-square in linear regression. Int. J. Math. Comput. 2013, 20, 84–93. [Google Scholar]
- Kuha, J. AIC and BIC: Comparisons of Assumptions and Performance. Sociol. Methods Res. 2004, 33, 188–229. [Google Scholar] [CrossRef] [Scilit]
- Pham, H. A New Criterion for Model Selection. Mathematics 2019, 7, 1215. [Google Scholar] [CrossRef] [Scilit]
- Pham, H. On Estimating the Number of Deaths Related to COVID-19. Mathematics 2020, 8, 655. [Google Scholar] [CrossRef] [Scilit]
- Xu, J.; Yao, S. Software Reliability Growth Model with Partial Differential Equation for Various Debugging Processes. Math. Probl. Eng. 2016, 2016, 1–13. [Google Scholar] [CrossRef] [Scilit]
- Pillai, K.; Nair, V.S.S. A model for software development effort and cost estimation. IEEE Trans. Softw. Eng. 1997, 23, 485–497. [Google Scholar] [CrossRef] [Scilit]
- Sharma, K.; Garg, R.; Nagpal, C.K.; Garg, R.K. Selection of Optimal Software Reliability Growth Models Using a Distance Based Approach. IEEE Trans. Reliab. 2010, 59, 266–276. [Google Scholar] [CrossRef] [Scilit]
- Kim, Y.S.; Song, K.Y.; Chang, I.H. Prediction and Comparative Analysis of Software Reliability Model Based on NHPP and Deep Learning. Appl. Sci. 2023, 13, 6730. [Google Scholar] [CrossRef] [Scilit]
- Ghorui, N.; Ghosh, A.; Algehyne, E.A.; Mondal, S.P.; Saha, A.K. AHP-TOPSIS Inspired Shopping Mall Site Selection Problem with Fuzzy Data. Mathematics 2020, 8, 1380. [Google Scholar] [CrossRef] [Scilit]
- Simjanovic, D.; Vesić, N.; Ignjatovic, J.; Randjelovic, B. A novel surface fuzzy analytic hierarchy process. Filomat 2023, 37, 3357–3370. [Google Scholar] [CrossRef] [Scilit]
- Sančanin, B.; Penjišević, A.; Simjanović, D.J.; Ranđelović, B.M.; Vesić, N.O.; Mladenović, M. A Fuzzy AHP and PCA Approach to the Role of Media in Improving Education and the Labor Market in the 21st Century. Mathematics 2024, 12, 3616. [Google Scholar] [CrossRef] [Scilit]
- Pham, H. A Logistic Fault-Dependent Detection Software Reliability Model. J. Univers. Comput. Sci. 2018, 24, 1717–1730. [Google Scholar] [CrossRef]
- Zolfani, S.; Yazdani, M.; Pamucar, D.; Zaraté, P. A VIKOR and TOPSIS focused reanalysis of the MADM methods based on logarithmic normalization. arXiv 2020, arXiv:2006.08150. [Google Scholar] [CrossRef] [Scilit]
- Taherdoost, H. Analysis of Simple Additive Weighting Method (SAW) as a MultiAttribute Decision-Making Technique: A Step-by-Step Guide. J. Manag. Sci. Eng. Res. 2023, 6, 21–24. [Google Scholar] [CrossRef] [Scilit]
- Song, K.Y.; Kim, Y.S.; Pham, H.; Chang, I.H. A Software Reliability Model Considering a Scale Parameter of the Uncertainty and a New Criterion. Mathematics 2024, 12, 1641. [Google Scholar] [CrossRef] [Scilit]
- Kim, Y.S.; Song, K.Y.; Pham, H.; Chang, I.H. Non-Homogeneous Poisson Process Software Reliability Model and Multi-Criteria Decision for Operating Environment Uncertainty and Dependent Faults. Appl. Sci. 2025, 15, 5184. [Google Scholar] [CrossRef] [Scilit]
- Tandon, A.; Singh, V.; Sharma, M.; Kumari, M. Entropy based Software Reliability Growth Modelling for Open Source Software Evolution. Teh. Vjesn. 2020, 27, 550–557. [Google Scholar] [CrossRef] [Scilit]
- Nikora, A.P.; Lyu, M.R. Software Reliability Measurement Experience. In Handbook of Software Reliability Engineering; Lyu, M.R., Ed.; McGraw-Hill: New York, NY, USA, 1996; p. 255. [Google Scholar]
- Hamby, D.M. A review of techniques for parameter sensitivity analysis of environmental models. Environ. Monit. Assess. 1994, 32, 135–154. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Li, X.; Xie, M.; Ng, S.H. Sensitivity analysis of release time of software reliability models incorporating testing effort with multiple change-points. Appl. Math. Model. 2010, 34, 3560–3570. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.