


Abstract
In this paper, we propose an efficient Nyström method with theoretical and empirical guarantees. In parallel computing environments and for sparse input kernel matrices, our algorithm can have computation efficiency comparable to the conventional Nyström method, theoretically. Additionally, we derive an important theoretical result with a compacter sketching matrix and faster speed, at the cost of some accuracy loss compared to the existing state-of-the-art results. Faster randomized SVD and more efficient adaptive sampling methods are also proposed, which have wide application in many machine-learning and data-mining tasks.
MSC:
68T05
1. Introduction
The Nyström method is a widely used technique to speed up kernel machines. Its efficiency in computation has attracted much attention in the past few years [1,2,3,4,5,6,7,8]. Given a kernel matrix , the Nyström method tries to approximate the kernel by random sampling to save computation cost. At the cost of computational efficiency, it suffers from a relatively large matrix approximation error in real applications [9,10]. Given the target rank k and target precision parameter , Wang and Zhang [4] gave a theoretical analysis that, with the Nyström method, it is impossible to obtain a bound relative to unless the number of sampled columns . Here, denotes the best rank-k approximation to the kernel matrix . Several modified Nyström methods were proposed in recent years [3,4,11,12]. In the work of [11], a modified Nyström method just needs columns of the kernel matrix to obtain a bound relative to . To the best of our knowledge, it is the fastest algorithm, costing to achieve a relative error of , where means the number of non-zero entries of . Although these modified Nyström methods are superior in approximation accuracy, it needs a much higher computational burden compared to the conventional Nyström method.
In this paper, we propose a much faster modified Nyström method which runs in time to achieve a bound relative to . When , our algorithm will be accelerated to
which is guaranteed by Lemma 3. Our algorithm is given in Algorithm 3. It needs times to conduct matrix multiplication which is easily implemented in parallel. The computation complexity of matrix multiplication in Algorithm 3 is near linear in input sparsity. In addition, for the arithmetic operations which are hard to implement in parallel, such as SVD, pseudoinverse and QR decomposition, Algorithm 3 needs time which is sublinear in the input size n. At the cost of sacrificing a certain accuracy, can be reached with the same computational complexity as the conventional Nyström method, needing arithmetic operations when sampling columns. Our empirical studies further validate the efficiency of our algorithm.
In this paper, we improve several key algorithms which constitute a faster modified Nyström method. We summarized our contributions as follow.
- First and most importantly, we propose an efficient modified Nyström method with theoretical guarantees.
- Second, a more computationally efficient adaptive sampling method is proposed in Lemma 2. Adaptive sampling is a cornerstone of column selection, CUR decomposition and the Nyström method [4,5,11,13], and it is also very popular in other matrix problems [14].
- Finally, our proposed practical Nyström method can achieve computation efficiency in real applications, as shown by our experiments.
The rest of this paper is structured as follows. In Section 2, we provide the notations used in this study. Section 3, several key algorithms that constitute the modified Nyström are improved. Section 4 gives our modified Nyström method. We conduct empirical analysis and comparison in Section 5, and conclude our work in Section 6. All detailed proofs are omitted except computation complexity analysis.
2. Notation and Preliminaries [15]
Firstly, we introduce the notation and concepts that will be utilized here and hereafter. is used to represent the identity matrix. Sometimes we just use for simplicity. We also use to signify a zero vector or a zero matrix with an appropriate size. The number of non-zero entries in is indicated by the notation .
Let and . The singular value decomposition (SVD) of may be expressed as
where the top k singular values are represented by (), () and (). The best (or closest) rank-k approximation to is denoted by . The i-th greatest singular value of is denoted by . The SVD is the same as the eigenvalue decomposition when is symmetric positive semi-definite (SPSD), in which case we obtain .
Furthermore, let be the Moore–Penrose inverse of , defined as . When is non-singular, the matrix inverse is the same as the Moore–Penrose inverse.
The matrix norms are defined in the manner as follows. Assume that the spectral norm is and the Frobenius norm is .
When given the matrices, and with , we explicitly define matrix as the closest representation of in the column space of with the rank of the most k. The function minimizes the residual across all in the column space of C. Here, “” denotes either the spectral norm or the Frobenius norm.
When given three matrices, , , and , the projection of onto ’s column space is represented as , and the one onto ’s row space is denoted by .
We now give the definition of leverage score sampling and subspace embedding, which are key tools to construct our Nyström algorithm.
Definition 1
(Leverage score sampling, [13,15]). Allow to be column orthonormal with , and to signify the i-th row of . Allow . Given that the are leverage scores, let r be an integer in the range . Create the sampling matrix and the rescaling matrix as follows. Pick an index i from the set of with probability , for each column of and , separately and with replacements. Let and . The number of operations required by this procedure is . This procedure is designated as
Definition 2
([16]). Assuming and , define a distribution on matrix as
, where ℓ depends on n, d, ε and δ. Assume that, any given matrix , with a probability of at least , a matrix chosen from distribution Π is a -subspace embedding for . Meaning that, for every , with probability . After that, we designate Π as an -oblivious -subspace embedding.
The sparse subspace embedding matrix and subsampled Hadamard matrix are the two most popular subspace embedding matrices. For an matrix with k dimension subspace, we can construct a sparse subspace embedding matrix for with rows, and the subsampled Hadamard matrix with [16]. Combining with still has the property.
Let’s discussed the computational costs about the matrix operations mentioned above. Matrix multiplication is an intrinsic parallel operation; hence, it can be easily implemented in parallel efficiently just as many mathematical software do. However, SVD decomposition and QR decomposition are much harder to implement in parallel. Hence, we denote the time complexity of such a matrix multiplication by . For a general matrix with , computing the full SVD requires flops, whereas computing the truncated SVD of rank k (), requires flops. Additionally, computing requires flops, too. Given a Hadamard–Walsh transform matrix , is the cost for the Hadamard–Walsh transform , which is substantially quicker than for the typical matrix multiplication. A sparse subspace embedding matrix for an matrix , needs arithmetic operations.
3. Main Lemmas and Theorems
In this part, we will outline our principal theorems and lemmas, which are the key tools to implement Algorithm 3. In addition, these lemmas and theorems are of independent interest and have wide application.
First, we give a fast randomized SVD method which is depicted in Algorithm 1 which is the fastest randomized SVD method as far as we know.
Lemma 1.
Given matrix , target rank k and error parameter , is returned from Algorithm 1; then, the following formula holds with high probability.
In addition, can be computed in . We denote Algorithm 1 as
| Algorithm 1 Sparse SVD |
|
Proof.
Lemma A2 shows that , where is of columns. Applying Lemma A1 and replacing with , we can obtain the result that
For computation time analysis, computing takes , and then computes the , where is the Cholesky decomposition of . Computing requires . Computing the SVD of requires . In addition, computing requires . Hence, Algorithm 1 takes
computation complexity. □
A faster adaptive sampling, Algorithm 2, is developed based on the work of [13]. Boutsidis and Woodruff [13] tried to compute norms of each column of . To further reduce the computation cost, we introduce the sketched to approximate . By such sketching, can be computed more efficiently than .
| Algorithm 2 Adaptive Sampling |
|
Lemma 2.
Given , and such that , with , let be returned from Algorithm 2 containing columns of . Then, the matrix satisfies that for any integer , and with a high probability which is at least .
In addition, this randomized algorithm can be implemented in
computation time. We denote this randomized algorithm as
Proof.
Let be the residual matrix and is the i-th column of . By Theorem A4, with high probability, it holds that
Besides, by the JL property of , we have . Hence, after utilizing the below distribution for sampling,
Using Lemma A3, we obtain
Using the Markov inequality, we have that
holds with a probability of at least .
As to the running time, it needs arithmetic operations to compute . To compute costs . To compute , it requires . In addition, computing and require and , respectively. In addition, to compute needs
computation. In addition, needs another arithmetic operations. Thus, all these need □
Lemma 3
([15,17]). Given the matrices , and , let’s suppose that is the leverage-score sketching matrix of with rows, and is the leverage-score sketching matrix of with columns. Let
and
then we can obtain
The number of sampled rows in Lemma 3 is independent on the input dimension of and is linear to c. By losing some accuracy, a much faster algorithm can be implemented.
4. Practical Modified Nyström Method
We use our new lemmas and theorems developed in Section 3 to implement an efficient modified Nyström algorithm.
4.1. Description of The Algorithm
A real symmetric matrix , an error parameter and a target rank k are the inputs of Algorithm 3. Meanwhile, a matrix with columns of , and a matrix are the results. There are primarily 3 steps in Algorithm 3: (i) using the definition of the leverage score sampling, it samples a number of columns of to obtain ; and using the adaptive sampling method to obtain and ; (ii) it calculates the leverage scores of using the method in [18]; and (iii) it constructs the intersection matrix . Note that in Lemma 3 is asymmetric even when is positive semi-definite. Thus, when applied to kernel approximation, we need to construct a positive semi-definite shown in Algorithm 3.
| Algorithm 3 Practical Nyström |
|
4.2. Analysis of Running-Time
Here, we provide a detailed analysis of the Algorithm 3’s arithmetic operations.
- 1
- The computation complexity of Algorithm 3 is to find columns of to construct .
- (a)
- To obtain from Theorem 1, it takes .
- (b)
- To obtain the leverage score and sample and , it takes .
- (c)
- To construct and Lemma 2, it takes .
- 2
- The computation complexity of Algorithm 3 is to construct when is the row dimension of and in Algorithm 3.
- (a)
- To obtain the leverage scores of , it takes .
- (b)
- To compute and , it takes .
- (c)
- To compute matrix multiplication, it takes .
- (d)
- To compute the eigenvalue decomposition of , it takes .
The algorithm’s overall asymptotic arithmetic operation is
4.3. Error Bound
Primary approximate result regarding Algorithm 3 is shown as the following theorem.
Theorem 1.
Given an error parameter ϵ and a target rank k, run Algorithm 3, then the below inequality holds with high probability.
5. Empirical Study
In this section, we compare our Practical Nyström algorithm with the uniform+adaptive algorithm [11,19], near-optimal+adaptive algorithm [4,11,13] and conventional Nyström using just uniform sampling. All algorithms were implemented in Matlab and experiments were conducted on a workstation with 32 cores of 2G Hz and 24G RAM.
On each data set, we give the approximation error and the execution duration of each algorithm. The approximation error is
where is the intersection matrix defined in the Nyström method.
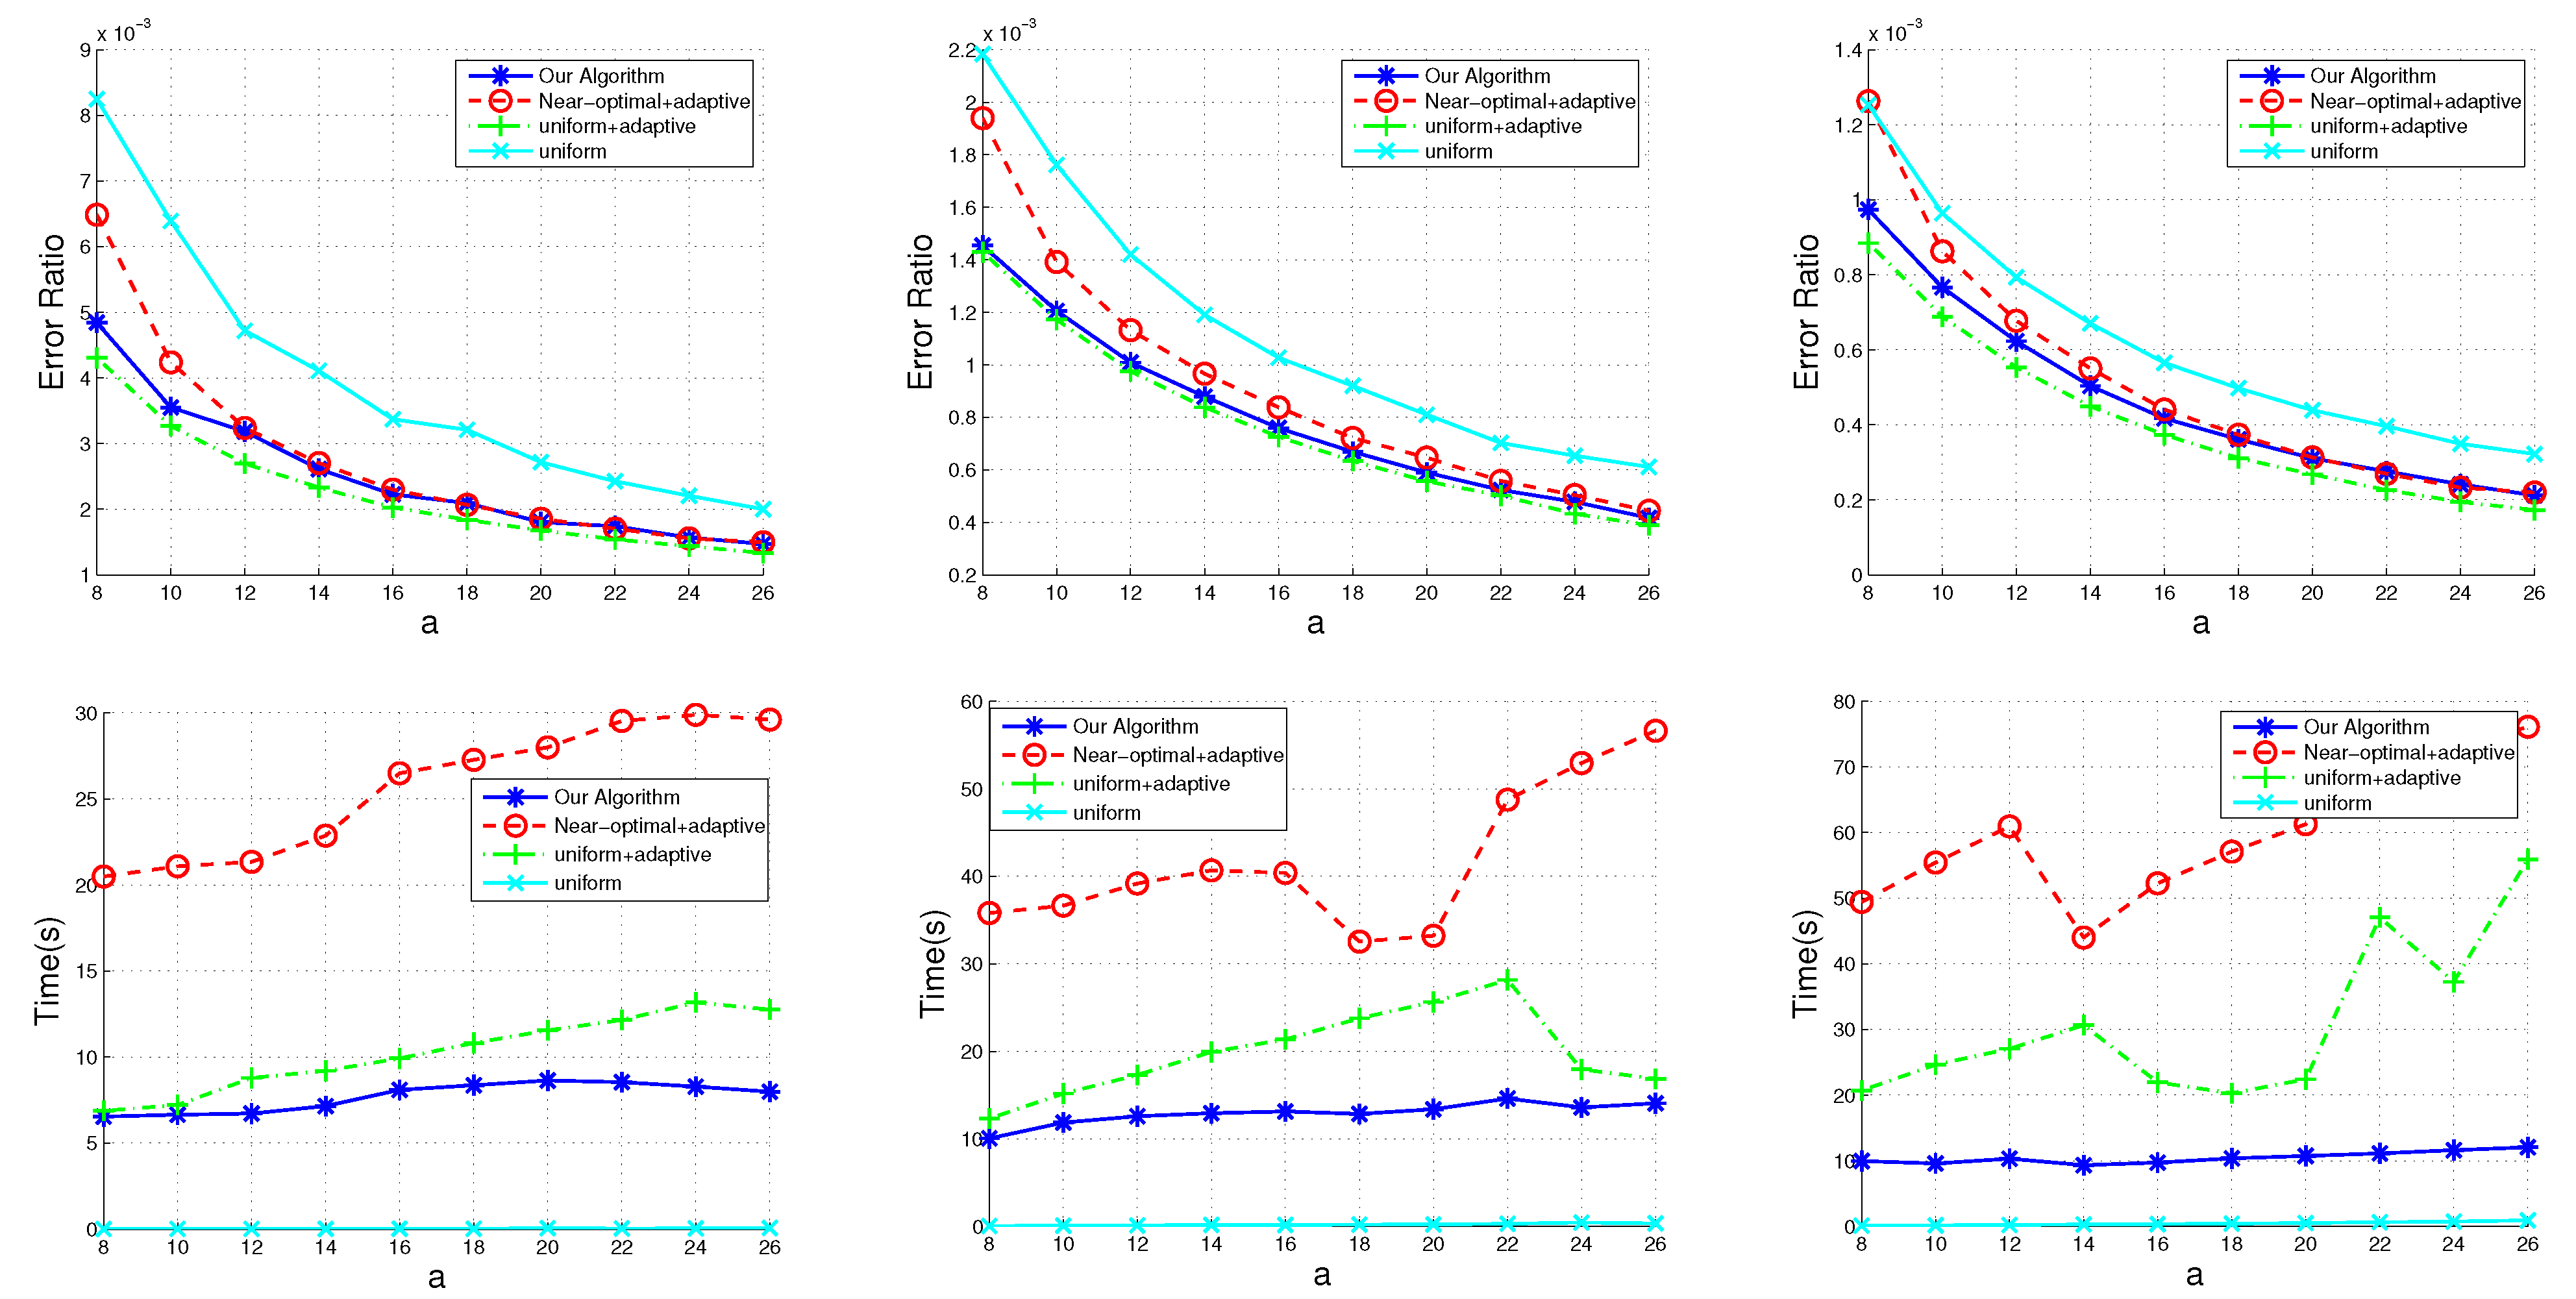
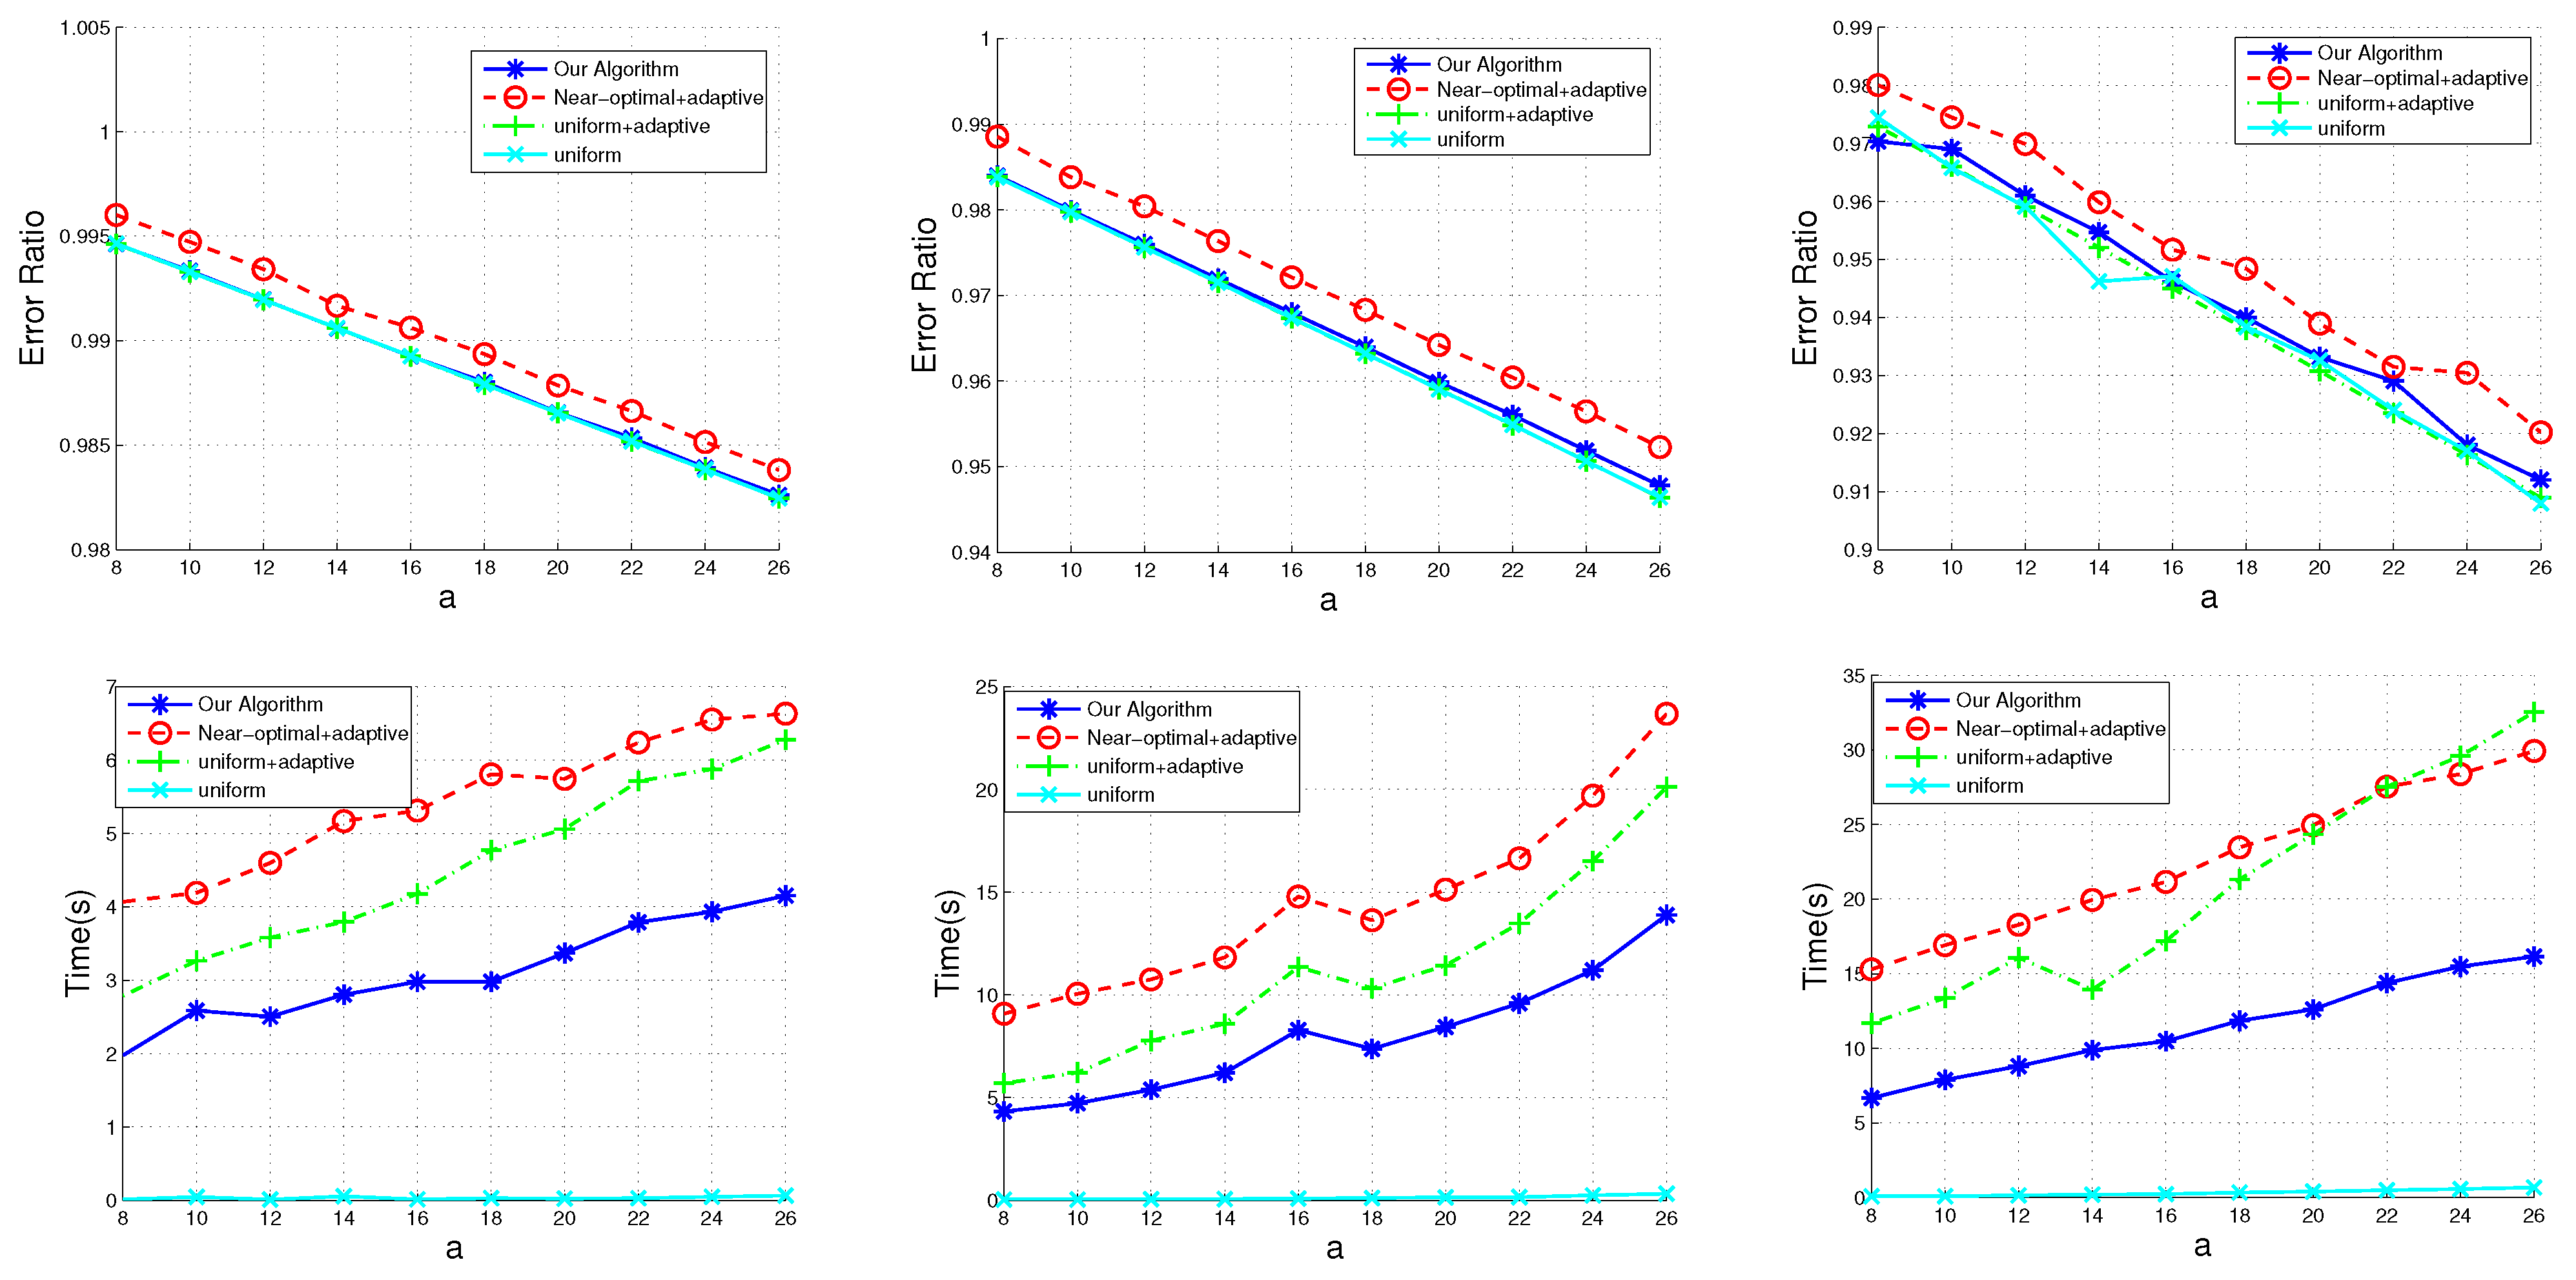
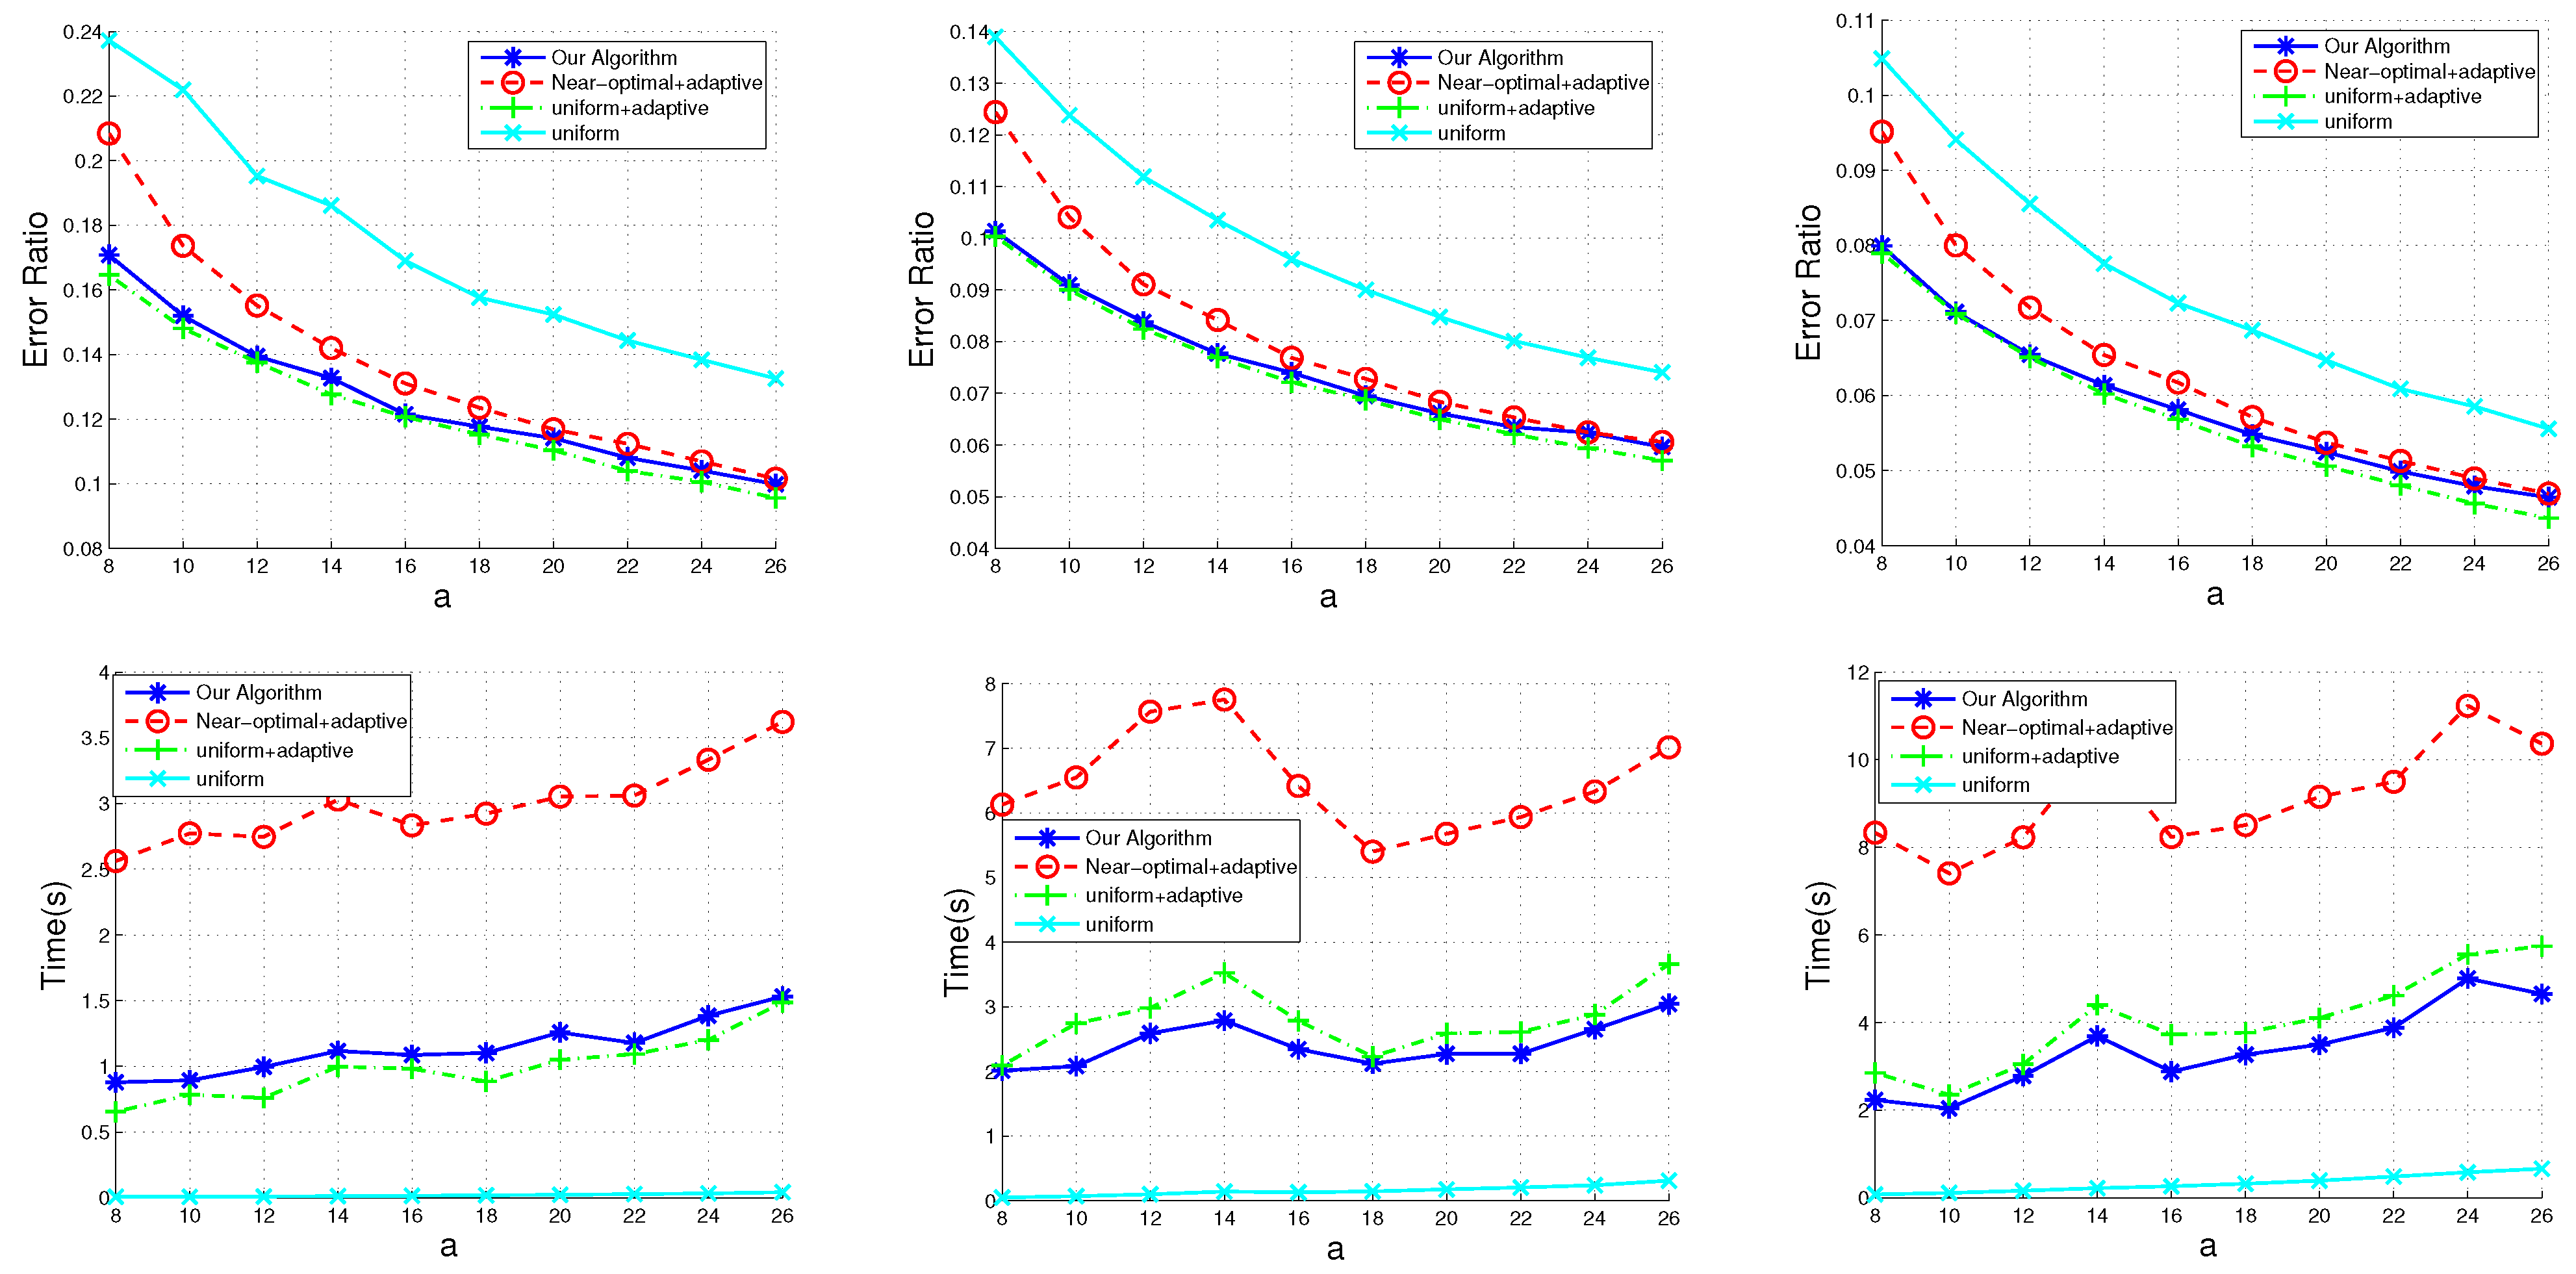
On three data sets we test all three algorithms, and the results are listed in Table 1. We create a RBF kernel matrix for each dataset, with , where and are data instances and is the parameter of the RBF kernel function. By the definition of , the size n of is the number of instances of the dataset. Thus, the kernel matrices in our experiments are of large sizes. We set different values for each data set as Table 1 describes. However, the effectiveness of our algorithm does not depend on the setting of . For each data set, we set and 50. We sampled columns from and a ranges from 8 to 26. We ran each algorithm 5 times and report the average value of approximation error and running time. All results are illustrated in Figure 1, Figure 2 and Figure 3.
Table 1.
A summary of the datasets for kernel approximation.
Figure 1.
Results of the Nyström algorithms on the a9a dataset. In the first column, we set , and with . In the middle column, we set , and . In the right column, we set , and .
Figure 2.
Results of the Nyström algorithms on the pendigit dataset. In the first column, we set , and with . In the middle column, we set , and . In the right column, we set , and .
Figure 3.
Results of the Nyström algorithms on the usps dataset. In the first column, we set , and with . In the middle column, we set , and . In the right column, we set , and .
As evidenced by the empirical results in the figures, it is clear that our approach is efficient. In terms of accuracy, Our approach is comparable to the state-of-the-art algorithm—the near-optimal+adaptive algorithm [4,11,13]. As to the running time, our approach is much faster than near-optimal+adaptive algorithm and uniform+adaptive algorithm. Our algorithm’s running time grows slower than the near-optimal+adaptive algorithm and uniform+adaptive algorithm. The advantage of the running time of our algorithm grows as the dimension of kernel matrix increases. Calculating kernel matrix of size from the ‘PenDigits’ data set, our alogrithm is twice as fast as the near-optimal+adaptive algorithm. As to the ‘a9a’ data set of 32,561 instances, our algorithm is four times faster than near-optimal+adaptive. In addition, as c increases, the running-time superiority of our algorithm also increases. Our algorithm also has similar a advantage over the uniform+adaptive algorithm. Hence, our algorithm is suitable to scale to kernel matrices of high dimensions.
6. Conclusions
In this paper, we proposed an efficient modified Nyström method with a theoretical and emperical guarantee. In a high-level parallel-computation environment with sparse input matrices, our Nyström method can achieve comparable computation efficiency compared to the conventional Nyström method, theoretically. Hence, our Nyström method is suitable for machine-learning algorithms in big-data setting. In addition, we give a sketching generalized matrix approximation which extends the previous work [12]. Faster randomized SVD and more efficient adaptive sampling methods are proposed which have wide application in lots of areas. In addition, our modified Nyström algorithm can be easily extended to CUR decomposition which leads to more efficient CUR decomposition.
Author Contributions
Conceptualization, W.Z. and Z.S.; methodology, W.Z. and J.L.; software, W.Z.; validation, S.C. and Z.S.; writing—original draft preparation, W.Z.; writing—review and editing, S.C.; visualization, J.L.; funding acquisition, Z.S. and S.C. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by Hangzhou Key Scientific Research Program of China (No. 20212013B06), Zhejiang Provincial Natural Science Foundation of China (No. LGG21E050005), National Natural Science Foundation of China (No. 61972208, No. 62272239 and No. 62022044) and National Natural Science Foundation of Jiangsu Province (No. BK20201043).
Acknowledgments
The authors would like to thank Professor An Yang, from Hangzhou Vocational & Technical College, for her valuable suggestions and guidance throughout this research.
Conflicts of Interest
The authors declare no conflict of interest.
Appendix A. Key Theorems Used in Our Proofs
Theorem A1
([15,20]). There is for matrix and orthonormal , thus, for a leverage-score sketching matrix for orthonormal ,
for any fixed .
Theorem A2
([15,20]). There is , for any rank k matrix with row leverage scores, such that leverage-score sketching matrix is an ϵ-embedding matrix for matrix , i.e.,
Theorem A3
([15,20]). Given that A is a matrix with m rows and C is a matrix with m rows as well as rank k. is a subspace embedding for with error parameter , and it is also the leverage-score sketching matrix of with rows. Then if and are respectively the solutions to
and
then, the below two formulas hold with a probability of at least .
Theorem A4
([15,20]). Given that A is a matrix with m rows, and C is a matrix with m rows as well as rank k, where with . is a subsampled randomized Hadamard matrix and is a sparse subspace embedding matrix with . Then if and are respectively the solutions to
and
then, the below two formulas hold with a probability of at least .
Lemma A1
([13,15]). Let and . Assume that given a particular rank parameter k and an accuracy parameter ,
is a QR-decomposition, and let where and . Let , where is a sparse subspace embedding matrix, and . Let contain the top k left singular vectors of Γ. Then, it holds that
with high probability.
Lemma A2
([16]). Given matrix , is a subspace embedding matrix with . is a sparse subspace embedding matrix with and is a subsampled randomized Hadamard matrix with . Let be the orthonormal basis of . Then, it holds that
with high probability.
Lemma A3
([4,15,16]). Given , and such that
with , given and the defined residual
For , let be the probability distribution such that for each i:
where is the i-th row of . Sample rows from in i.i.d. trials, where in each trial the i-th column is chosen with probability . Let contain the sampled rows and let . Then
Theorem A5
([13,15]). Given three matrices , and , we have
Theorem A6
([15,21]). Given a matrix , where and , let be any matrix such that rank . Let . Then
Appendix B. Theorem 1 Proof
We first provide an essential lemma before proving the theorem.
Lemma A4
([15]). Given any , and , assume . Let be a projection matrix. Then
Now we start to prove Theorem 1.
Proof.
According to Theorem A6, we have
Let and , then we have
because of Lemma A1 with error parameter . In addition, is a row leverage score sketching matrix of , where , and are calculated in Algorithm 3. Additionally, is also a subspace embedding matrix of with error parameter . Inferring from the fact that , we obtain
where Equation (A2) follows from the fact that , and Equation (A3) follows from Theorem A1 with error parameter and . Due to Theorem A2 with error parameter , Equation (A4) can be obtained. Because we have
therefore,
Due to Theorem A2, needs columns as a subspace embedding matrix of with error parameter . Theorem A2 also leads to in the proof of Equation (A3). Now we have
where the last inequality follows from Equation (A1) and .
Using Lemma 2, we need to sample columns from such that has the property
Lemma A1 shows that there exists an othonormal matrix with rank k in the range of such that
, and we define , then by Lemma A3, it holds that
By rescaling the , we can obtain a relative error bound. Since , Lemma A4 leads to
Inferring from the fact that and , utilizing Lemma A4 twice, we reach the result that
is a leverage-score sketching matrix of , when is the row dimension of ; by Theorem 3 of [12], we have,
By rescaling , we achieve the final result that
□
References
- Kumar, S.; Mohri, M.; Talwalkar, A. Sampling methods for the Nyström method. J. Mach. Learn. Res. 2012, 13, 981–1006. [Google Scholar]
- Williams, C.; Seeger, M. Using the Nyström method to speed up kernel machines. In Proceedings of the 14th Annual Conference on Neural Information Processing Systems, Vancouver, BC, Canada, 3–8 December 2001; Number EPFL-CONF-161322. pp. 682–688. [Google Scholar]
- Gittens, A.; Mahoney, M.W. Revisiting the Nyström Method for Improved Large-Scale Machine Learning. arXiv 2013, arXiv:1303.1849. [Google Scholar]
- Wang, S.; Zhang, Z. Improving CUR Matrix Decomposition and the Nyström Approximation via Adaptive Sampling. J. Mach. Learn. Res. 2013, 14, 2729–2769. [Google Scholar]
- Anderson, D.G.; Du, S.S.; Mahoney, M.W.; Melgaard, C.; Wu, K.; Gu, M. Spectral Gap Error Bounds for Improving CUR Matrix Decomposition and the Nyström Method. In Proceedings of the AISTATS, San Diego, CA, USA, 9–12 May 2015. [Google Scholar]
- Wang, S.; Gittens, A.; Mahoney, M.W. Scalable kernel K-means clustering with Nyström approximation: Relative-error bounds. J. Mach. Learn. Res. 2019, 20, 431–479. [Google Scholar]
- Gao, S.; Dou, S.; Zhang, Q.; Huang, X. Kernel-Whitening: Overcome Dataset Bias with Isotropic Sentence Embedding. arXiv 2022, arXiv:2210.07547. [Google Scholar]
- Hamm, K.; Lu, Z.; Ouyang, W.; Zhang, H.H. Boosting Nyström Method. arXiv 2023, arXiv:2302.11032. [Google Scholar]
- Hsieh, C.J.; Si, S.; Dhillon, I.S. Fast Prediction for Large-Scale Kernel Machines. In Proceedings of the Advances in Neural Information Processing Systems, Montreal, QC, Canada, 8–13 December 2014; pp. 3689–3697. [Google Scholar]
- Si, S.; Hsieh, C.J.; Dhillon, I. Memory efficient kernel approximation. In Proceedings of the 31st International Conference on Machine Learning, Beijing, China, 21–26 June 2014; pp. 701–709. [Google Scholar]
- Wang, S.; Luo, L.; Zhang, Z. SPSD Matrix Approximation vis Column Selection: Theories, Algorithms, and Extensions. J. Mach. Learn. Res. 2016, 17, 1697–1745. [Google Scholar]
- Wang, S.; Zhang, Z.; Zhang, T. Towards More Efficient SPSD Matrix Approximation and CUR Matrix Decomposition. J. Mach. Learn. Res. 2016, 17, 1–49. [Google Scholar]
- Boutsidis, C.; Woodruff, D.P. Optimal CUR Matrix Decompositions. SIAM J. Comput. 2017, 46, 543–589. [Google Scholar] [CrossRef] [Scilit]
- Deshpande, A.; Vempala, S. Adaptive sampling and fast low-rank matrix approximation. In Approximation, Randomization, and Combinatorial Optimization. Algorithms and Techniques; Springer: Berlin/Heidelberg, Germany, 2006; pp. 292–303. [Google Scholar]
- Ye, H.; Li, Y.; Zhang, Z. A simple approach to optimal CUR decomposition. arXiv 2015, arXiv:1511.01598. [Google Scholar]
- Woodruff, D.P. Sketching as a tool for numerical linear algebra. arXiv 2014, arXiv:1411.4357. [Google Scholar]
- Ye, H.; Wang, S.; Zhang, Z.; Zhang, T. Fast Generalized Matrix Regression with Applications in Machine Learning. arXiv 2019, arXiv:1912.12008. [Google Scholar]
- Drineas, P.; Magdon-Ismail, M.; Mahoney, M.W.; Woodruff, D.P. Fast approximation of matrix coherence and statistical leverage. J. Mach. Learn. Res. 2012, 13, 3475–3506. [Google Scholar]
- Wang, S.; Zhang, Z. Efficient Algorithms and Error Analysis for the Modified Nystrom Method. In Proceedings of the Seventeenth International Conference on Artificial Intelligence and Statistics, Reykjavik, Iceland, 22–25 April 2014; pp. 996–1004. [Google Scholar]
- Clarkson, K.L.; Woodruff, D.P. Low rank approximation and regression in input sparsity time. In Proceedings of the Forty-Fifth Annual ACM Symposium on Theory of Computing, Palo Alto, CA, USA, 2–4 June 2013; pp. 81–90. [Google Scholar]
- Boutsidis, C.; Drineas, P.; Magdon-Ismail, M. Near-optimal column-based matrix reconstruction. SIAM J. Comput. 2014, 43, 687–717. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2023 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).