


Abstract
With the proliferation of multimodal content on social media, creators increasingly require tools that can retrieve both images and videos relevant to a single textual query. However, existing cross-modal retrieval methods are typically confined to binary (text–image or text–video) settings and struggle with fine-grained semantic alignment and spatiotemporal information imbalance. To address this issue, we propose UniTriM, a unified framework for text–image–video joint retrieval. First, UniTriM supports concurrent retrieval of semantically relevant images and videos given one textual input. To overcome the scarcity of text–image–video triplet data, we introduce a self-attention-based keyframe selection strategy that converts existing text–video datasets into triplet format. Second, we design a multi-granularity similarity alignment module that captures hierarchical semantics by modeling patch–frame–video and word–triple–sentence structures and jointly optimizes intra- and cross-granularity alignments to enhance fine-grained cross-modal correspondence. Third, to alleviate the inherent spatiotemporal information imbalance between static images and video-aligned text descriptions, we introduce a feature disentanglement module that disentangles spatial-related features from text and aligns them explicitly with image representations. Experiments conducted on three benchmark datasets MSR-VTT, MSVD, and DiDeMo demonstrate that UniTriM achieves state-of-the-art performance on joint retrieval tasks.
1. Introduction
With the proliferation of social media platforms (e.g., TikTok, Xiaohongshu, Facebook), information has exhibited exponential growth and increasingly complex multimodal combinations [1]. This phenomenon poses challenges for general users in managing information overload and creates filtering difficulties, while content creators face inefficiencies in retrieving and organizing vast quantities of multi-source data. To engage a wider audience on social media, creators have shifted from text-centric posts to integrated multimedia formats. Readers seeking an overview can grasp the results at a glance through images, while those interested in details can understand the behavioral processes and context of events through videos. However, given the vast volume of data, how creators can quickly locate the required data to enhance the timeliness and sustainable output capacity of content creation has become an issue that needs to be addressed. Unlike typical text–image or text–video binary retrieval tasks, creators require the simultaneous retrieval of both images and videos using a textual query.
However, previous research in constructing multimodal datasets has often treated image and video data separately. Current datasets predominantly consist of either text–video pairs or text–image pairs, lacking comprehensive datasets that simultaneously include text, image and video. This further intensifies the challenges of cross-modal retrieval, especially when multi-target retrieval needs to be conducted within a unified semantic space. Social media creators frequently require both images and videos related to the same theme or event during actual content creation. For example, searching with the keyword “urban sunrise” to obtain both stunning images capturing the moment of sunrise and video clips documenting the sunrise process. The available data may represent different perspectives or varying temporal granularities of the same event. This raises the question of how to accurately capture such fine-grained semantic correlations.
Existing models that support both text–image and text–video retrieval can be broadly grouped into two classes. The first type does not involve training on text–video pairs directly. Instead, these approaches transfer models pre-trained on large-scale image–text pairs directly to video tasks. For instance, mPLUG [2] and BLIP [3] first pre-train a foundational model for cross-modal understanding and generation between images and texts. To process videos, they uniformly sample frames, encode each frame independently using the pre-trained image encoder, and then fuse the frame-level features to form a global video representation via average pooling. However, this method inherently ignores the temporal dynamics between video frames, resulting in limited representational capacity for video content. This limitation is particularly problematic in scenarios that require capturing action sequences or the progression of events. The second category of methods involves training on text–video datasets. These approaches typically introduce dedicated temporal modeling modules designed specifically for video understanding. For example, OmniVL [4] employs a decoupled joint training strategy. It learns spatial representations from image–text datasets and temporal dynamics from video–text datasets. Similarly, mPLUG2 [5] designs a unified architecture with a shared spatial encoder for both images and videos to process spatial information, while an additional localized temporal modeling module is incorporated specifically for videos to capture motion and changes. However, a common limitation of these existing methods is their predominant focus on global representations, which often overlooks fine-grained visual details.
To address the above challenges, we propose UniTriM, which is a unified framework for text–image–video joint retrieval. The framework is designed to simultaneously retrieve relevant images and videos from a unified repository using a single textual query. The goal of this framework is to provide social media creators with an efficient, accurate, and semantically consistent tool for multimodal material retrieval. Due to the scarcity of text–image–video triplet data, we introduce a self-attention-based method that calculates inter-frame similarities within a video to identify representative keyframes, which are then treated as static images. This effectively augments existing text–video datasets into text–image–video triplet datasets. Compared to arbitrary static images, these keyframes are not only more content-aligned with the source video but also more likely to correspond to its textual description, serving as a high-level summary of the video. By augmenting data in this way, our framework enables users to retrieve both relevant images and videos through a unified textual input.
Current multi-granularity alignment models [6,7,8] either employ an insufficient number of granularity levels or focus solely on same-granularity alignment, neglecting the potential of cross-granularity interactions for enhanced information filtering. Inspired by brain-inspired learning mechanisms [9,10] which indicates that humans process video–text correspondence through multi-level interactions, we extract multi-granularity representations for each modality: a patch–frame–video three-level structure for video, and a word–triple–sentence three-level structure for text. These representations explicitly model the inherent hierarchical semantic structures in both video and text data. Building upon this representation, we design a multi-granularity similarity alignment module to capture cross-modal semantic relationships more comprehensively. The module computes cross-granularity similarities to secure basic semantic consistency and simultaneously performs same-granularity alignment to overcome the limitations of ignoring detailed information, thereby constructing more robust and comprehensive multimodal semantic associations. This multi-level alignment strategy also facilitates more effective learning of spatial information by the image encoder.
In the proposed text–image–video paradigm, a spatiotemporal information imbalance exists between the textual descriptions and the static keyframe images, since the descriptions are annotated for the dynamic video content. The text describing a video encompasses both its spatial and temporal information semantically. In contrast, images are static and only possess spatial features. Inspired by MAP-IVR [11], which decomposes video features into appearance features and motion features, we adopt a feature disentanglement module to extract the spatial-related features from the text and align them with the image features. This module thereby mitigates the inherent information imbalance issue in the constructed text–image–video triplet data.
The principal contributions of this work are highlighted as follows:
- We propose a text–image–video retrieval model, UniTriM, which enables simultaneous retrieval of both images and videos via textual queries. To achieve this, we introduce a self-attention-based construction method that derives text–image–video from existing text–video data.
- We design a multi-granularity similarity alignment mechanism. By incorporating multi-granularity representations for each modality and performing both same-granularity and cross-granularity alignment, our method constructs more effective and robust cross-modal semantic associations.
- We introduce a feature disentanglement module to disentangle spatial-related features from the video description and aligns them with image features, thereby addressing the spatiotemporal information imbalance between images and texts in the data.
2. Related Work
2.1. Multi-Modal Retrieval
Multimodal retrieval refers to the task of information retrieval across different modalities. Unlike traditional single-modal information retrieval, multimodal retrieval can process and integrate data from different modalities to provide more comprehensive, accurate, and enriched retrieval results. The primary bottlenecks in multimodal retrieval include structural heterogeneity and the semantic gap [12,13].
Alec Radford et al. [14] designed CLIP, a large-scale image–text approach based on contrastive learning. CLIP encodes text and images into a shared high-dimensional semantic representation space and achieves modality alignment through a mutual-information-based contrastive objective within that space, thereby transforming the problem of structural heterogeneity into one of representation learning and distribution alignment. CLIP demonstrates outstanding performance across tasks in various domains and exhibits strong transfer and generalization capabilities. Following this, works such as CLIP4Clip [15], Clip2Video [16], VideoCLIP [17], and ActionCLIP [18] have adapted CLIP for text–video retrieval tasks by transferring knowledge from the image–text domain to the video–text domain using the pre-trained CLIP model in an end-to-end manner. Approaches like mPLUG [2] and BLIP [3] first train a foundational model primarily for cross-modal understanding and generation between image and text. For videos, they uniformly sample frames, encode each frame independently using an image encoder, and then aggregate the frame-level features into a global video representation via average pooling before interacting with textual information. While these methods successfully transfer pre-trained image–text models to text–video tasks, their ability to capture video-specific characteristics remains limited, as the underlying models were originally trained only on image–text pairs.
OmniVL [4] uses a transformer-based universal architecture capable of accommodating both image–text and video–text tasks. It introduces a decoupled joint training approach. The model is first pre-trained on image–text datasets such as MS-COCO to focus on learning spatial representations, and subsequently jointly pre-trained with video–text datasets such as MSR-VTT to progressively learn temporal dynamics while refining the previously acquired spatial representations. Similarly, mPLUG2 [5] employs a unified architecture for visual encoding, where a shared transformer module processes spatial information for both images and videos. To specifically handle temporal dynamics, it incorporates an additional module to model motion and changes in videos.
Although the aforementioned methods incorporate temporal information learning for videos, they primarily capture global features while overlooking fine-grained details. Moreover, these approaches typically require separate processing of text–image and text–video datasets during training, which introduces a dataset gap. Image datasets tend to emphasize static scenes and object recognition, whereas video datasets are more concerned with dynamic behaviors and event progression. Such domain divergence makes it hard to balance the semantic characteristics of both images and videos in joint retrieval tasks, ultimately compromising overall retrieval accuracy and consistency.
2.2. Multi-Granularity Alignment Approach
In recent years, research in the text–video retrieval field has progressively shifted from coarse-grained global alignment toward more refined multi-granularity semantic alignment. Multi-granularity methods achieve enhancement through multi-level feature alignment or fusion, capturing semantic correlations between videos and texts at both holistic and local levels.
HANet [19] introduces a hierarchical alignment mechanism, which separates video and text into three semantic granularities: event, action, and entity. By establishing alignment signals at different semantic levels, it enhances fine-grained capability in cross-modal matching. Subsequently, Tencent HCMI [7] further proposes a multi-level representation interaction framework. Leveraging self-attention mechanisms, it adaptively clusters semantics into hierarchical structures. Alignment tasks are then established between corresponding levels, frame–word, segment–phrase, and video–sentence. MVLI [20] constructs a multi-stage grouped interaction framework, designing a token grouping block that employs Gumbel–softmax to separately cluster semantically similar video frames and text words. By establishing multi-level alignments at the scene, action, and object levels, it further enhances fine-grained semantic matching.
X-CLIP [6] proposes an end-to-end framework for multi-granularity contrastive learning. It computes similarities at four levels: video–sentence, video–word, sentence–frame, and frame–word, enabling simultaneous local semantic, global semantic, and cross-granularity contrastive learning. This design captures semantic consistency across multiple levels. TC-MGC [21] introduces text-conditioned multi-granularity contrastive learning, where the input text dynamically guides the selection of relevant visual granularities, achieving a semantically adaptive alignment strategy. UCoFiA [8] proposes a coarse-to-fine alignment framework, establishing alignment from video–sentence to frame–sentence, and down to patch–word level. To address the issue of overlooked feature interaction during cross-modal similarity alignment, UCoFiA further introduces a feature interaction mechanism that jointly considers cross-modal relevance and inter-feature interactions, thereby improving the accuracy of similarity alignment. Moreover, MSNet [22] presents a multi-granularity network that integrates hierarchical aggregation with semantic similarity optimization, further advancing fine-grained cross-modal correspondence modeling.
The methods discussed above exhibit certain limitations, some [7,19,20] focus exclusively on same-granularity alignment while entirely neglecting cross-granularity relationships. Others [6,8,21] lack sufficient granularity refinement, for example, by overlooking fine-grained patch–word alignment, which are critical for capturing detailed visual semantics. These constraints may hinder the model’s capacity to fully capture and align multimodal content across varying levels of abstraction.
2.3. Feature Disentanglement
Feature disentanglement refers to the separation of multiple latent factors in data into independent representations, particularly in the field of representation learning within machine learning. VDSM [23] is an unsupervised video disentanglement method that employs state-space modeling and a mixture-of-experts decoder to separate time-varying latent factors from static scene content in videos. DEVIAS [24] proposes a novel encoder–decoder architecture designed to learn disentangled representations of actions and scenes, aiming to mitigate the scene bias issue in video recognition models where action representations are influenced by contextual scenes. COMD [25] introduces a training-free video motion transfer model. Based on motion cues in the background, it separates moving objects from the background by solving Poisson equations, estimates camera motion within the moving object regions, and can decouple camera and object motion from source videos, subsequently transferring the extracted camera motion to new videos. DRL [26] presents a disentanglement framework that captures both sequential and hierarchical representations. Taking advantage of the inherent sequential structure in text and video inputs, it utilizes a weighted token-level interaction module to decompose content and adaptively leverage pairwise correlations. MAP-IVR [11] disentangles video representations into motion and appearance components, extracts appearance features from images, and subsequently improves disentanglement quality through an image-to-video transformation process.
From the perspective of the task formulation, our disentanglement requirement is similar to the research objective of MAP-IVR. MAP-IVR disentangles a video into appearance features and motion features via two independent decoders. We adapt this encoder framework to correspondingly disentangle textual descriptions into spatial-related and temporal-related semantic features.
3. Methodology
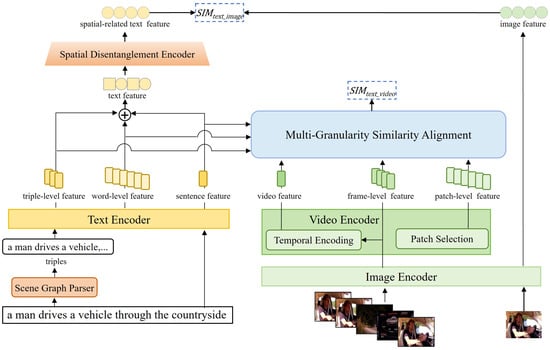
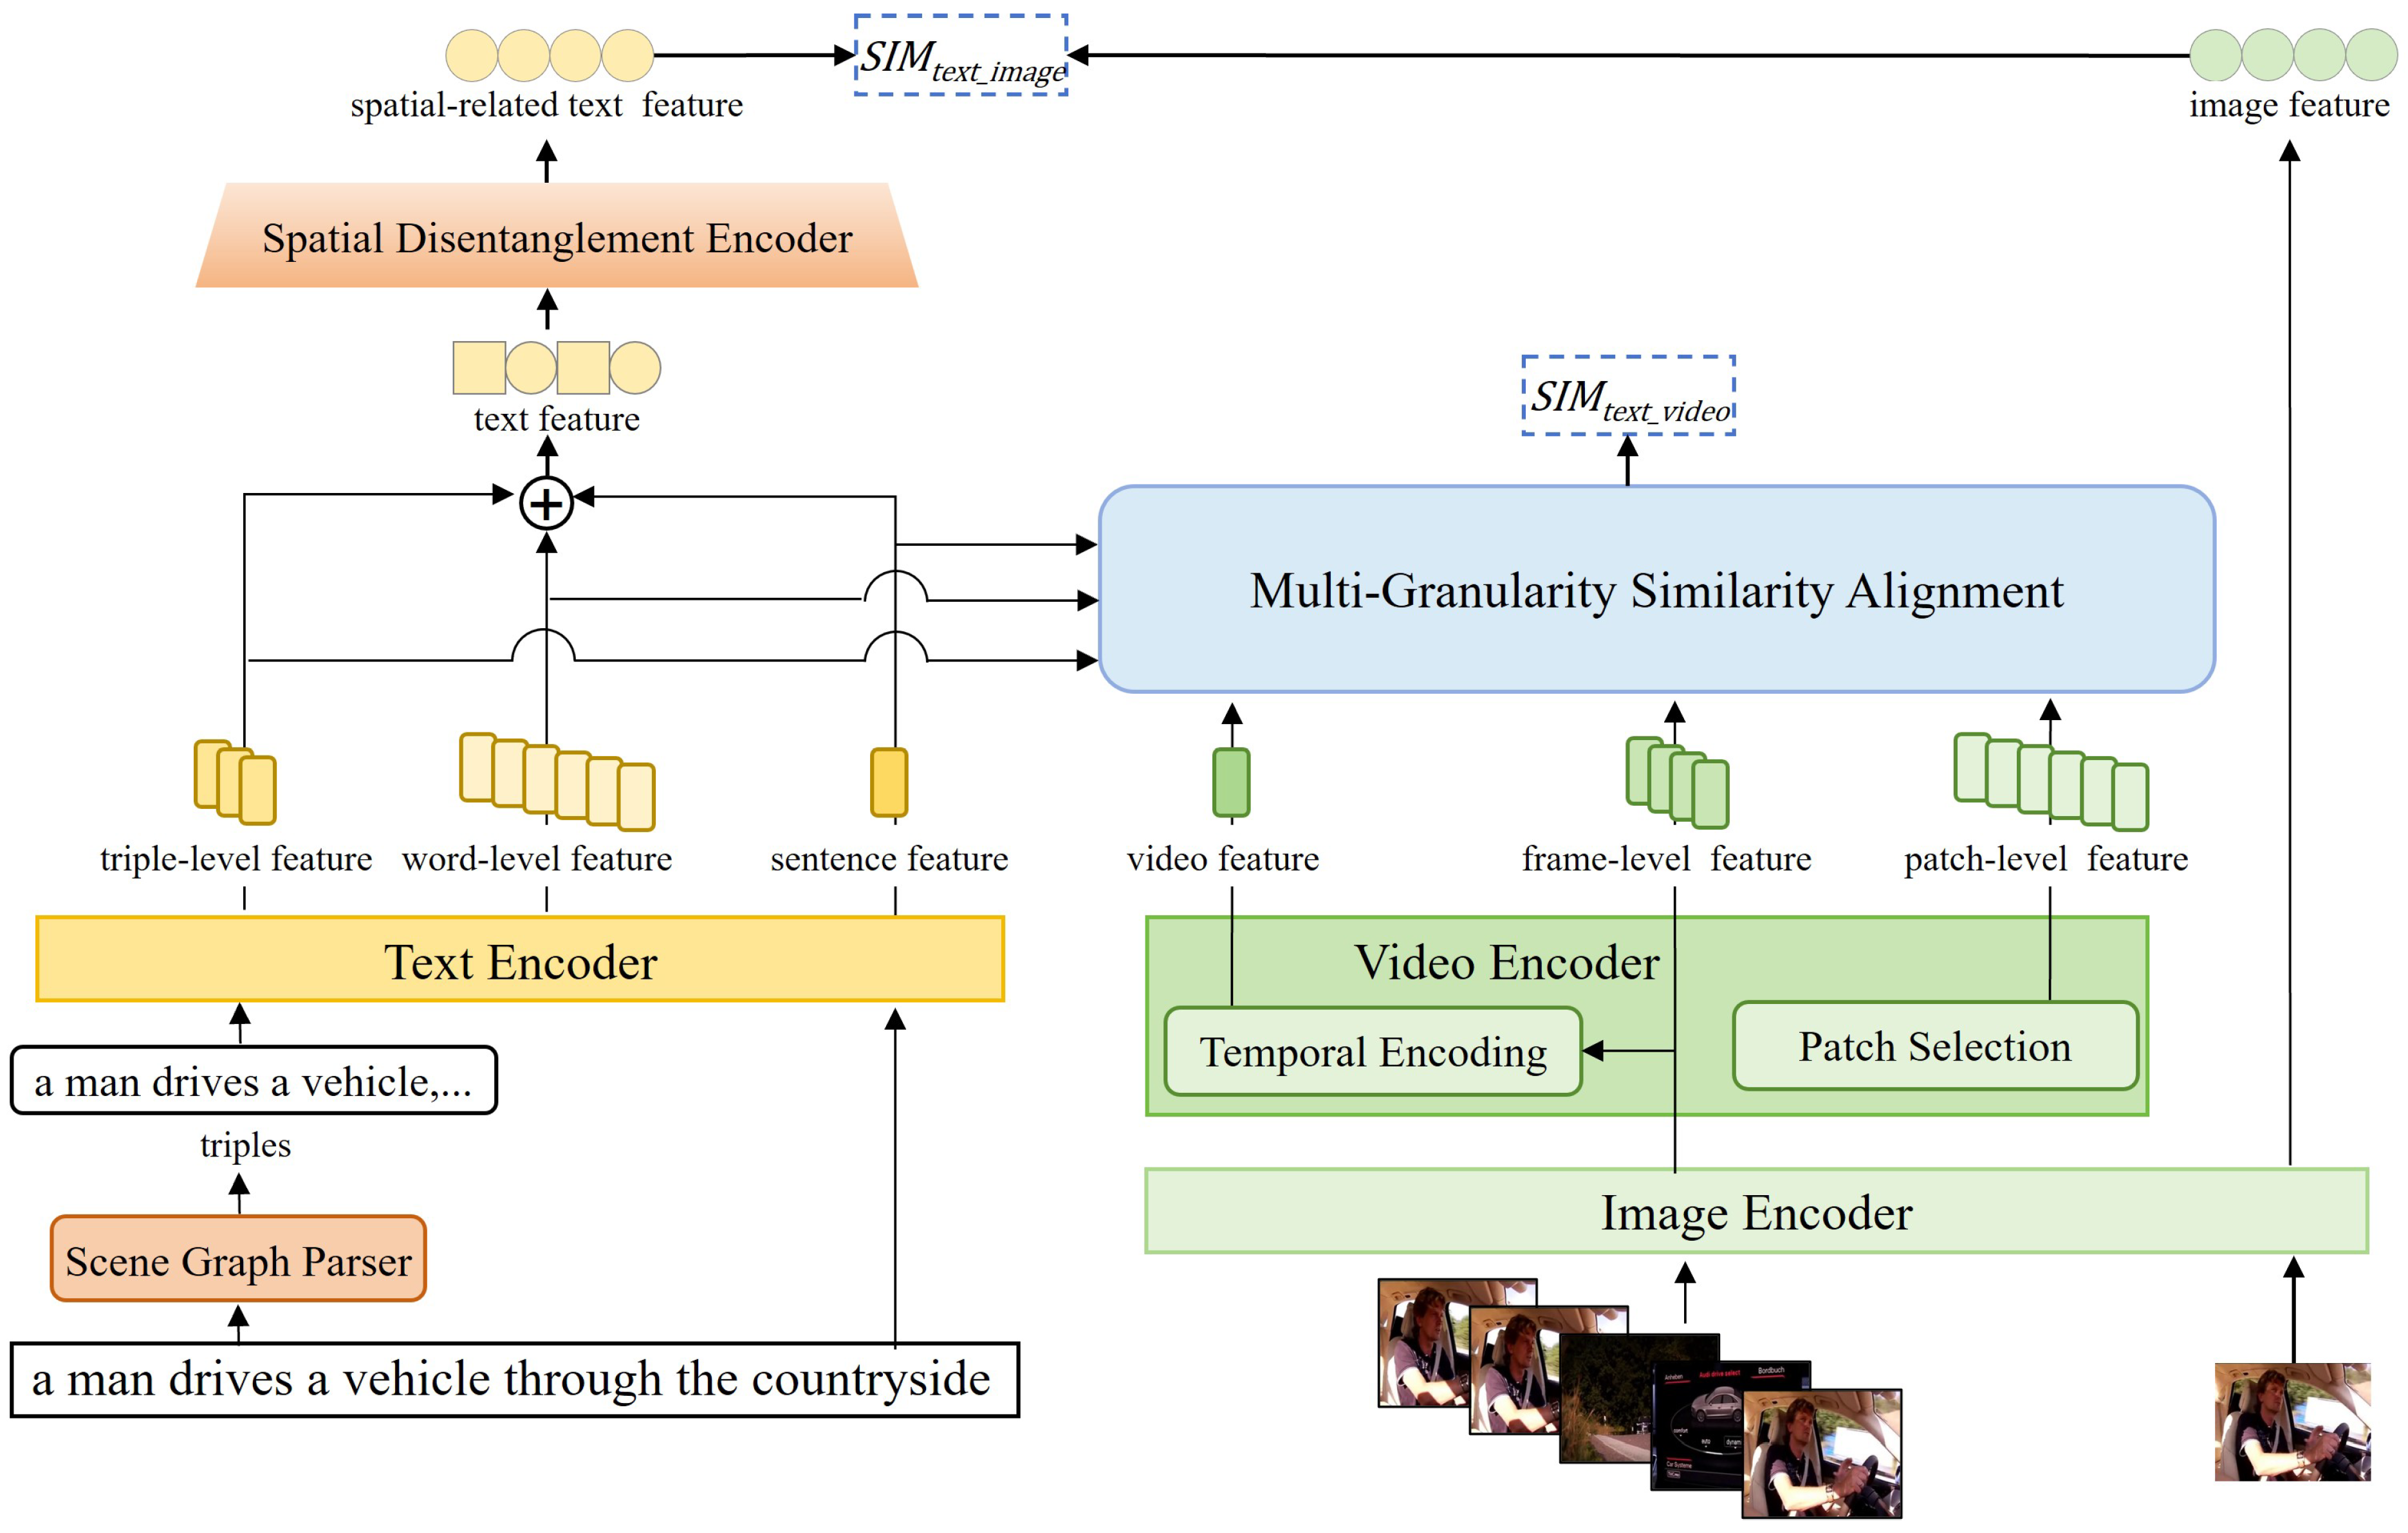
This section details the architecture of UniTriM for efficient joint text–image–video retrieval. The overall framework is depicted in Figure 1.
Figure 1.
Architecture of the retrieval framework UniTriM. First, multi-granularity feature representations for text, images, and videos are learned separately through a text encoder, an image encoder, and a video encoder. Then, the multi-granularity similarity alignment module retrieves videos matching the text. Next, it fuses the multi-granularity textual representations via weighting to form a unified text feature. Finally, the text feature is processed by a spatial disentanglement encoder to extract spatial-related text features, which are used to retrieve corresponding images based on the spatial information in the text.
The framework first extracts features from each modality. An image encoder extracts spatial features from images as well as video frames. For videos, these spatial features are further fed into a video encoder to learn temporal information, yielding multi-granularity video representations. For text, a scene graph parser extracts structured triplets, which, along with the raw text, are input to a text encoder to obtain multi-granularity textual features. The multi-granularity features of text and video are then passed into a multi-granularity similarity alignment module. This module performs multi-level semantic alignment to retrieve videos that match the textual description. Subsequently, the multi-granularity textual features are merged to construct a unified text representation that comprehensively integrates multi-level semantics. Finally, this unified text representation is input into a spatial disentanglement encoder, which separates explicit spatial-related features. These features are then matched against the image features to complete spatial-based image retrieval.
Specifically, Section A elaborates on the extraction of multi-granularity representations for text, image, and video data. Section B describes the architecture of the multi-granularity similarity alignment module. Section C introduces the design principles and training methodology of the feature disentanglement mechanism. Finally, Section D systematically presents the compound optimization objectives and loss function framework.
3.1. Multi-Granularity Representations
The proposed framework leverages the inherent structural characteristics of text, image, and video modalities. Text and video are represented at three hierarchical semantic levels, whereas the image modality employs a global representation. For text, this hierarchical representation includes word-level, triplet-level, and sentence-level representations. Correspondingly, video data adopt a parallel three-level structure comprising patch-level, frame-level, and video-level representations.
3.1.1. Multi-Granularity Text Representation
Existing multi-granularity alignment methods, such as X-CLIP [6], typically employ only word-level and sentence-level text representations. While word-level representations provide fine-grained object-specific information, they often suffer from semantic ambiguity due to the lack of contextual information. Conversely, sentence-level representations capture broader contextual semantics but may overlook critical fine-grained details. To mitigate this issue, we introduce triplet-level representations that explicitly model entity-relation structures with structured semantic clarity, thereby enhancing domain-relevant knowledge. We employ the Stanford Scene Graph Parser [27] to automatically extract triplets. This yields both relational (entity–relation–entity, e.g., man, riding, bicycle) and attributive (entity–attribute–value, e.g., car, color, blue) triplets. In our framework, both types are treated uniformly without distinction.
Typically, the CLIP text encoder is employed to generate textual representations. For an input text, the encoder produces word-level representations , where is the sequence length and d denotes the feature dimension. The token provides a global sentence-level representation , where d denotes the feature dimension. Concurrently, the text is parsed by a scene graph parser to extract m structured triplets. These m triplets are independently encoded by the same CLIP text encoder, and their corresponding m tokens are collected to form the triplet-level embedding matrix .
3.1.2. Multi-Granularity Video Representation
To capture the spatiotemporal characteristics and hierarchical semantics of video data, UniTriM models video representations using a patch–frame–video hierarchical structure, corresponding to the patch-level, frame-level, and video-level representations. An ordered sequence of n frames is obtained via uniform sampling. Each frame is partitioned into patches, which are encoded by a ViT-based encoder to produce patch embeddings . The token of each frame provides its frame-level representation . To capture temporal dependencies inherent in videos, the model incorporates a temporal encoder that processes sequential frame representations. After processing frame features through the temporal encoder, a global video representation is obtained. Furthermore, given the high redundancy among adjacent patches, a patch selection module selects the top-k salient patch embeddings from to form the compact patch-level representation . The detailed designs of the temporal encoder module and the patch selection module are described below.
Temporal Encoding Module. Video sequences inherently possess an ordered frame structure, while standard image encoders lack the capability to model temporal dynamics. To capture such temporal dependencies, we add a temporal encoding module on top of the spatial features. The module adopts a Transformer encoder architecture designed to process the sequence of frame-level representations. Through the self-attention mechanism, it establishes inter-frame dependencies and captures the evolution of actions and the progression of events within the video. The formulation of the temporal module is formulated as follows:
where denotes the l-th transformer layer, denotes the frame representations at the lth layer, and represents the learnable position embedding vectors, which are used to preserve temporal order.
Patch Selection Module. Although the temporal encoder captures inter-frame dynamics, it operates solely on frame-level tokens, potentially leading to the loss of fine-grained spatial details. To incorporate richer visual semantics, our framework leverages patch-level tokens. However, not all patches carry equally salient information, and the high similarity among adjacent patches across both spatial and temporal dimensions introduces significant redundancy if all patches are processed indiscriminately. To resolve this, we design a learnable patch selection module Mselect with a multilayer perceptron (MLP) architecture. This module dynamically selects the most salient patches by computing per-patch saliency scores, thereby obtaining patch features with higher information density. The computation proceeds as follows.
First, the similarity score between each local patch and the global video representation is computed as:
where denotes the patch embedding at position j of frame i in , and is the global video representation, denotes vector concatenation, and , are learnable projection matrices. Based on these scores, the top-k patches are chosen to form the salient patch-level representation :
3.1.3. Image Representation
The image representation is obtained straightforwardly from the pre-trained ViT-B/32 model by using its token as the global image representation .
3.2. Multi-Granularity Similarity Alignment
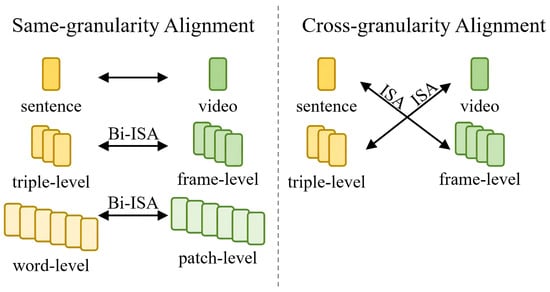
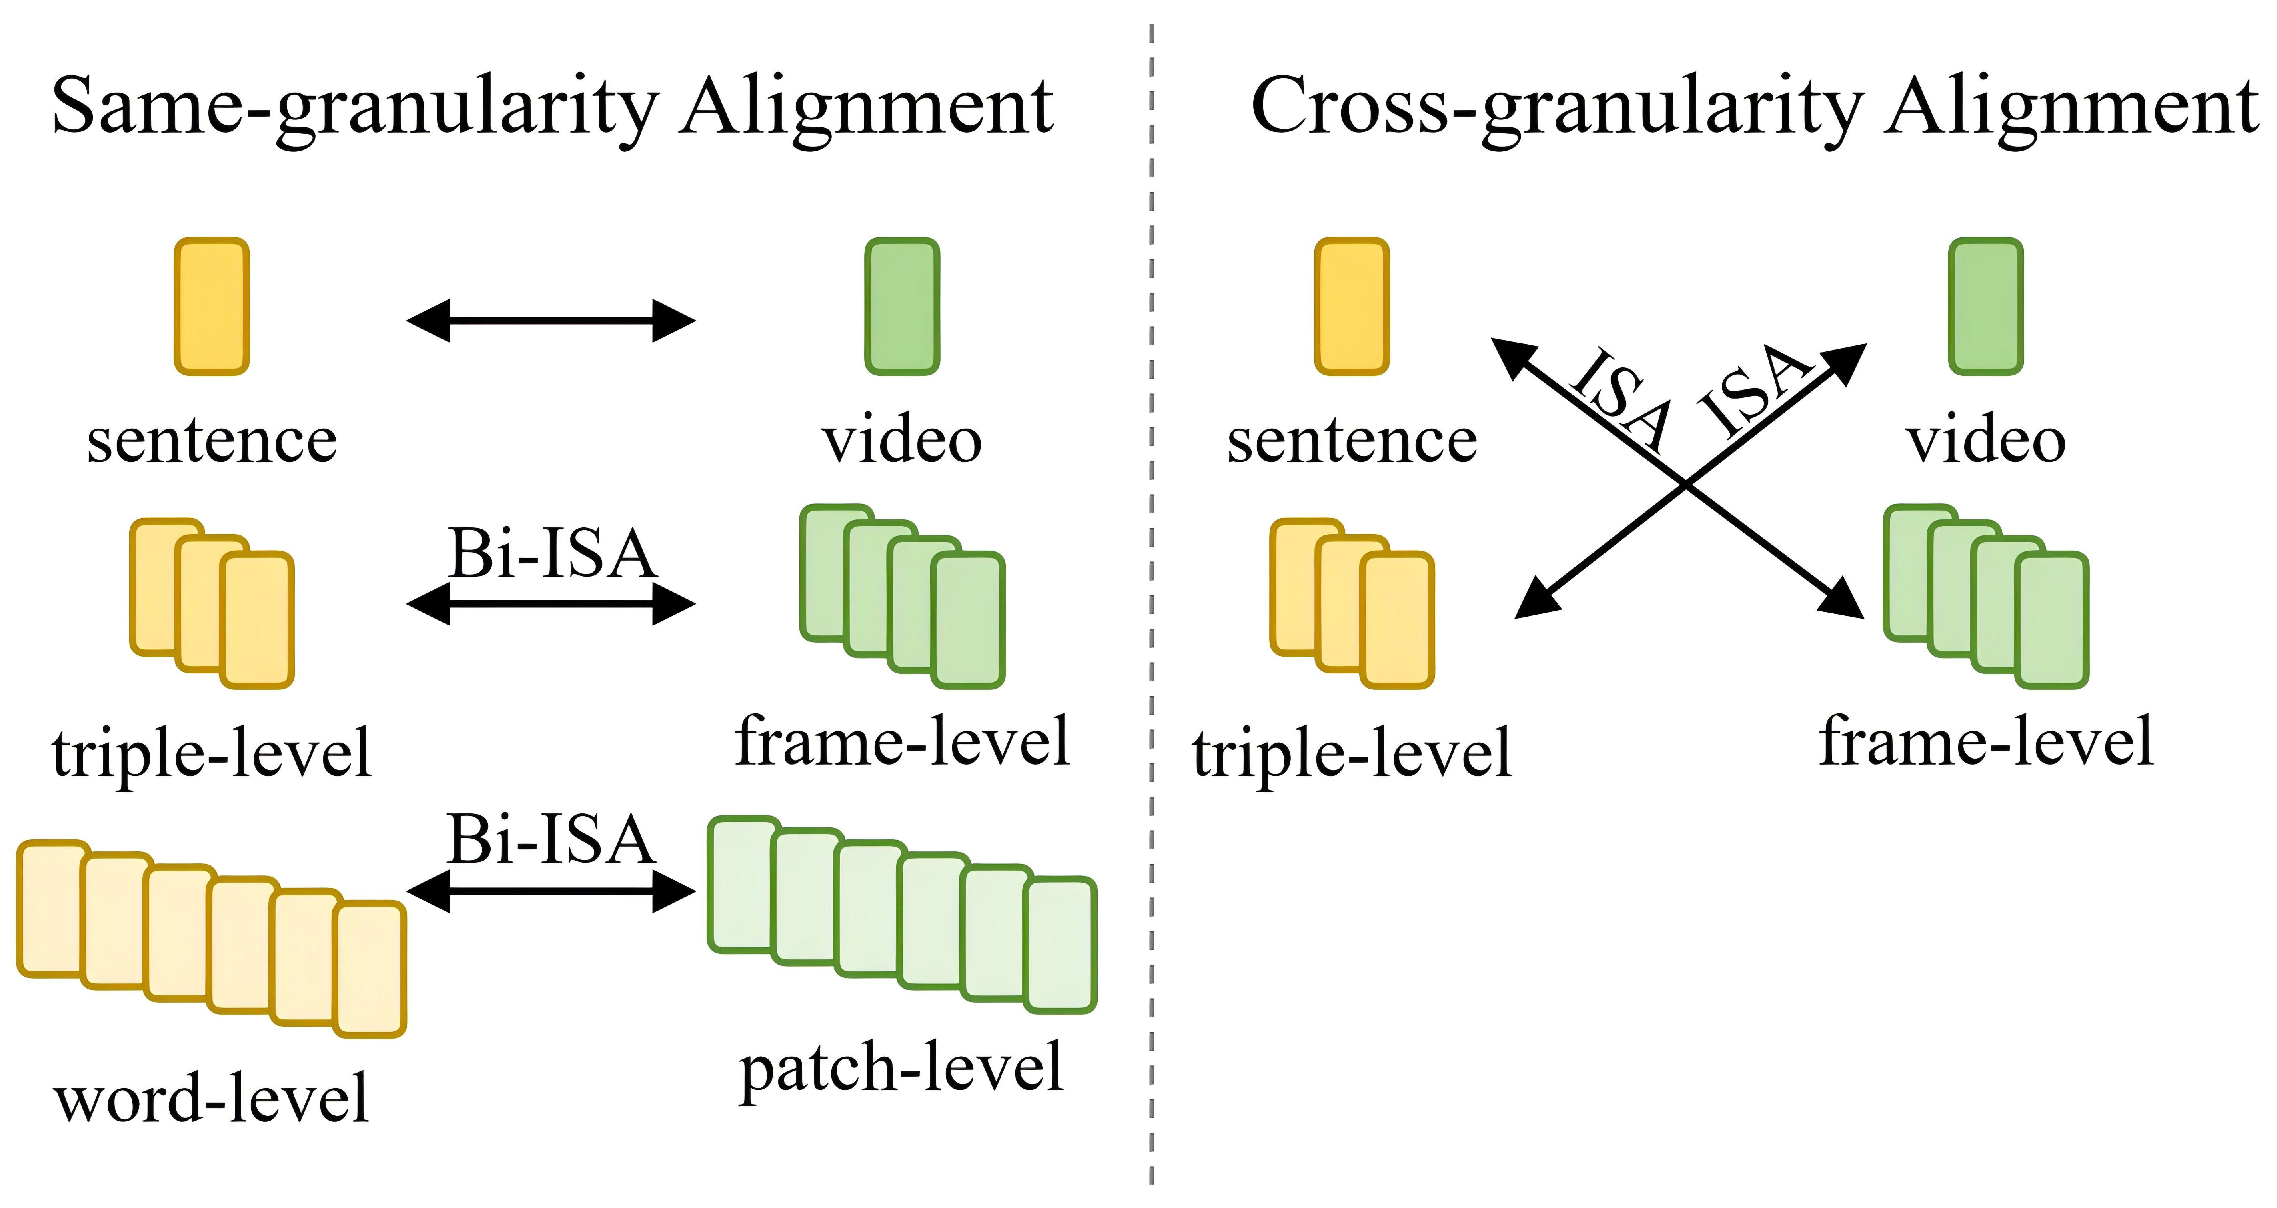
Existing text–video retrieval methods predominantly rely on either global-level matching or high-level semantic alignment. These approaches either overlook fine-grained cues or only achieve single-granularity alignment. To address this, we introduce a Multi-Granularity Similarity Alignment (MGSA) mechanism which constructs a hierarchical alignment network, as illustrated in Figure 2. The MGSA mechanism consists of two complementary components: same-granularity alignment and cross-granularity alignment.
Figure 2.
Multi-Granularity Similarity Alignment. Same-granularity alignment: sentence–video (between global sentence and global video features), triplet–frame (between text triplets and video frame features), word–patch (between words and patch features). Cross-granularity alignment: sentence–frame (between global sentence and video frame features), triplet–video (between text triplets and global video features).
3.2.1. MGSA Module Overview
Same-Granularity Alignment. At this level, MGSA establishes three refined matching relationships. First, sentence–video alignment captures the overall semantic relevance between the full text and the entire video. Second, triplet–frame alignment focuses on the correspondence between structured textual triplets and frame-level content in the video. Third, word–patch alignment matches the finest textual tokens with local visual details in video.
Cross-Granularity Alignment. This strategy enhances the inter-level semantic association and complementarity. On one hand, sentence–frame alignment enables the model to relate the overall textual description to specific frame content in the video sequence. On the other hand, triplet–video alignment associates structured local semantics in text with the overall theme or scene of the video, enriching the hierarchy of semantic understanding.
3.2.2. Interactive Similarity
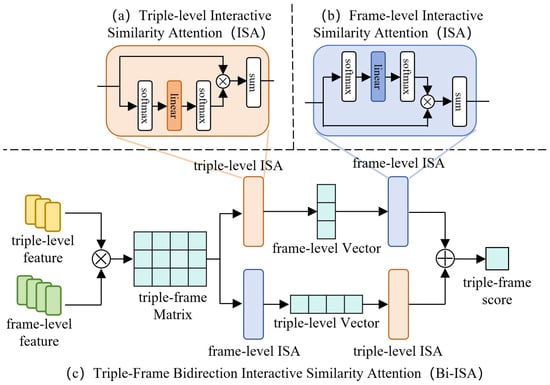
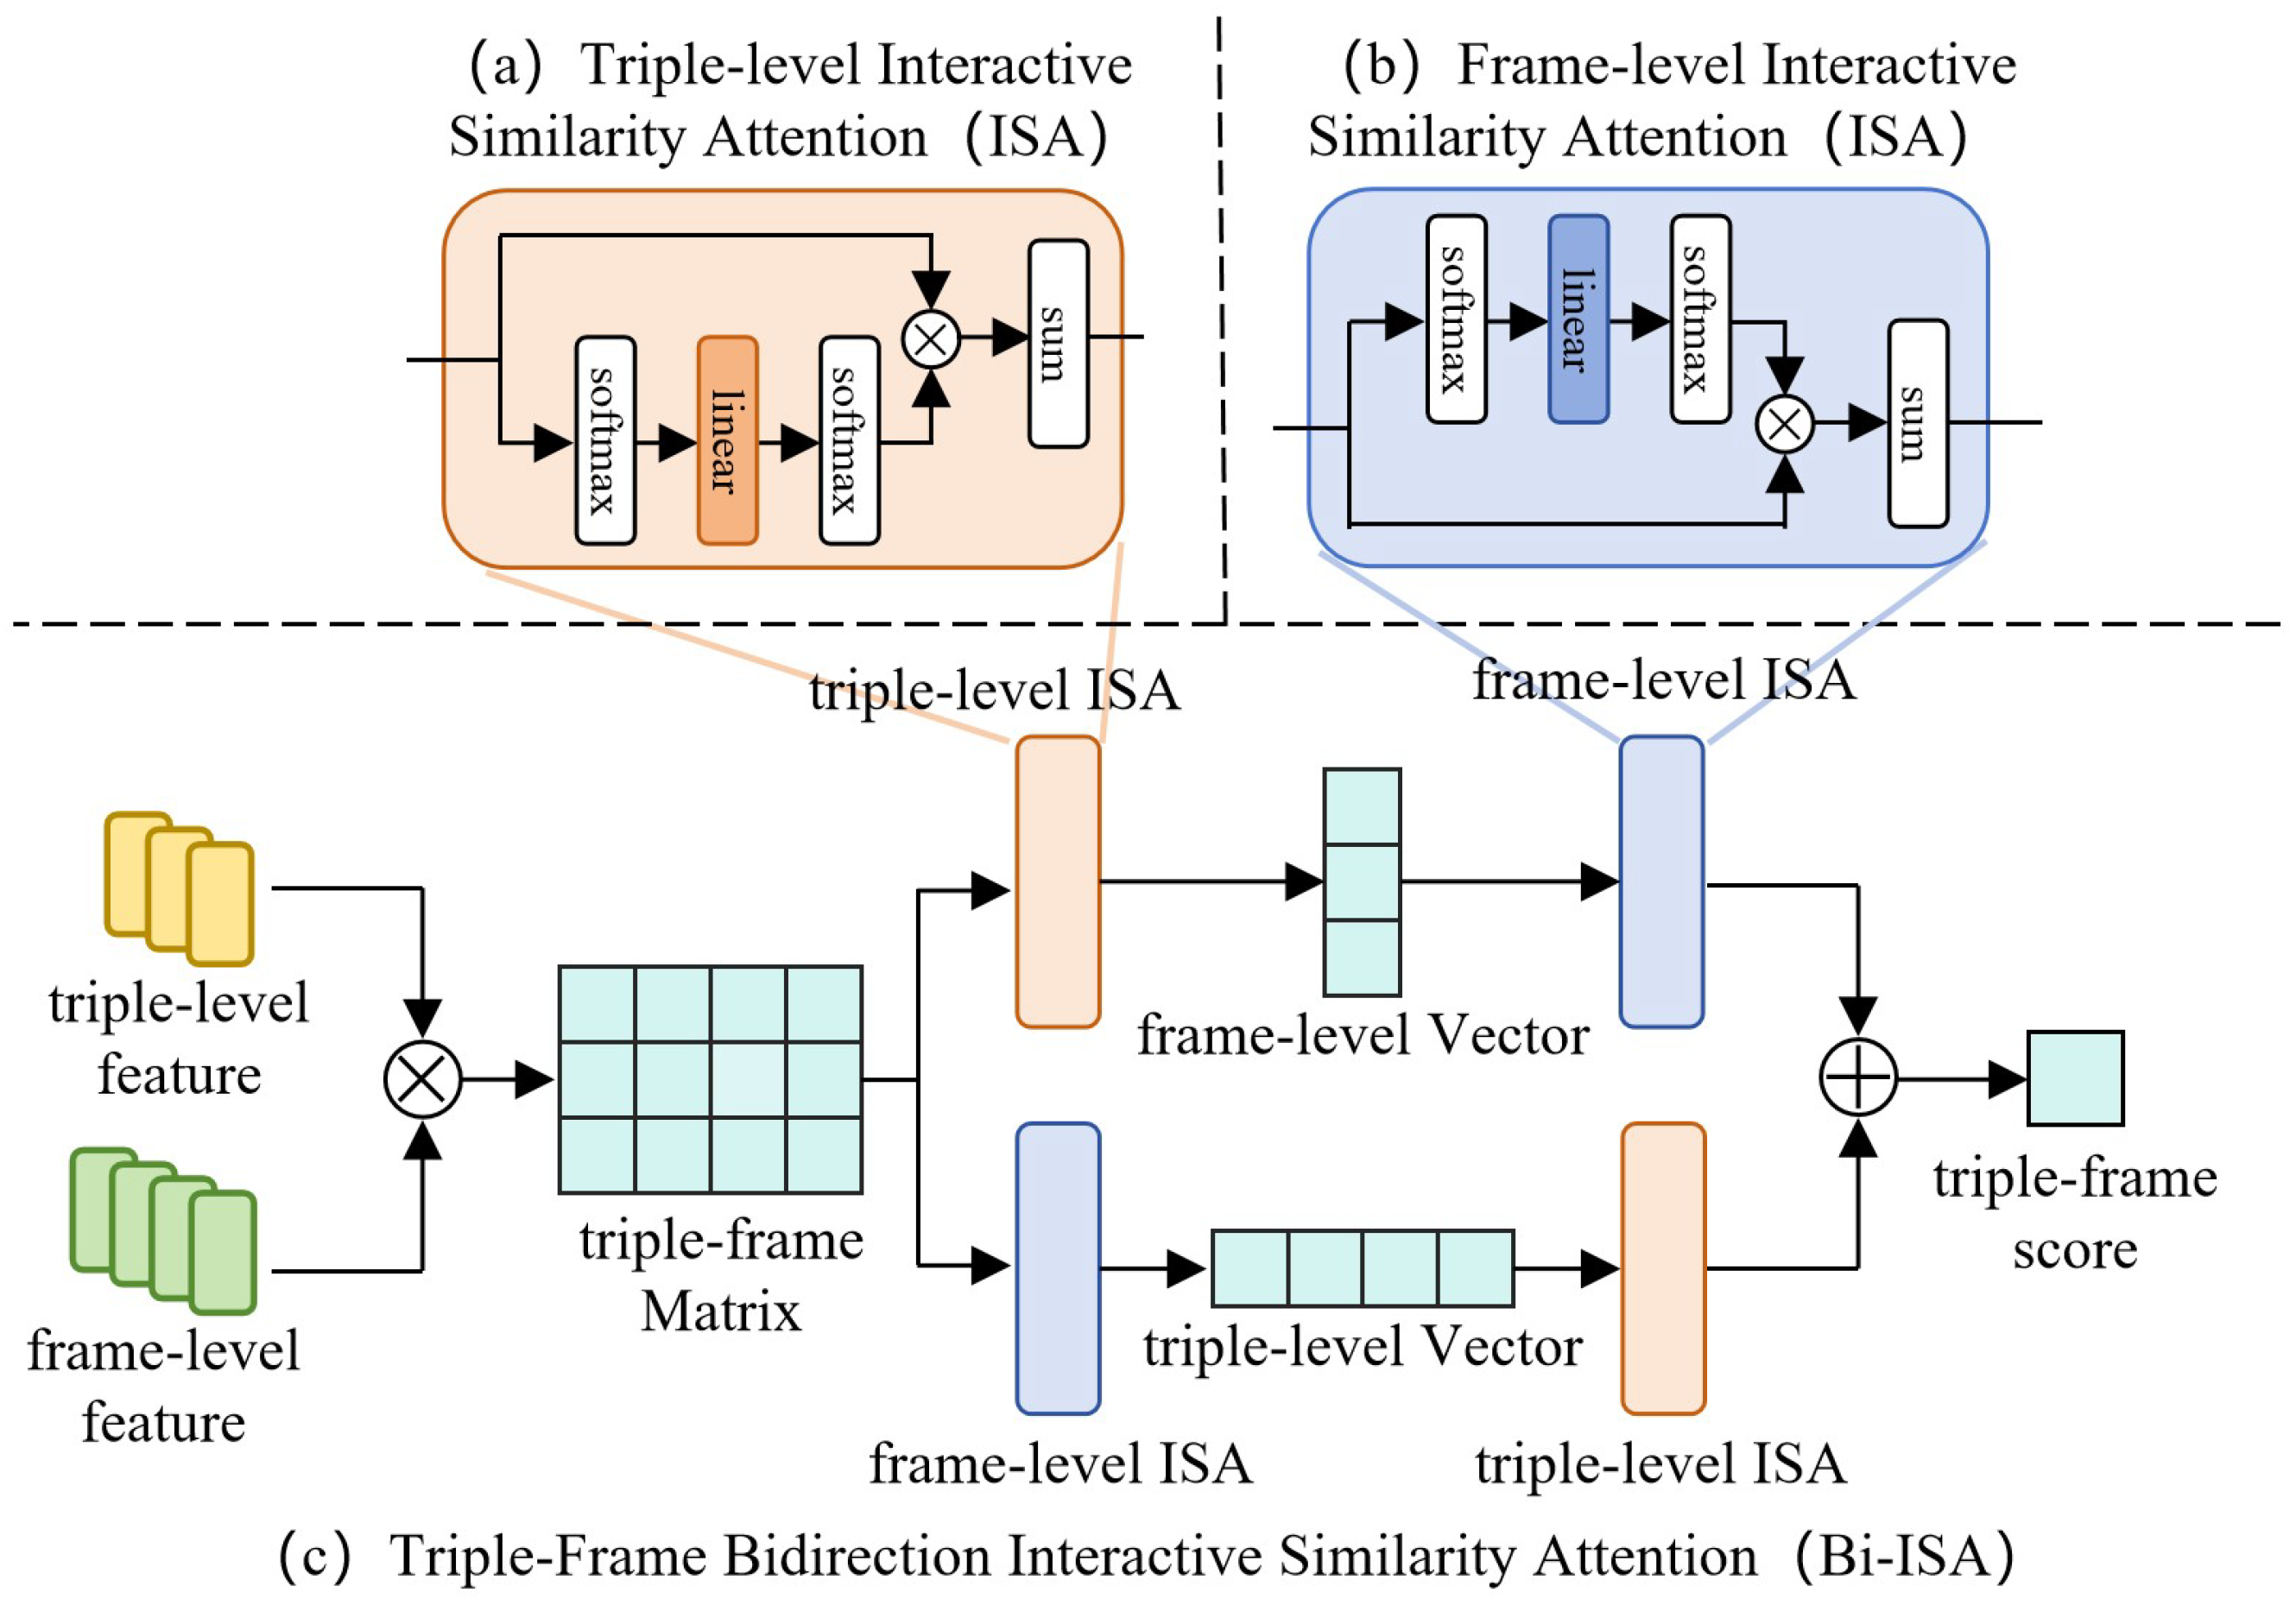
To efficiently compute the multi-granularity similarities and enable deep cross-modal interaction, we adopt the Interactive Similarity Attention (ISA) and Bidirectional Interactive Similarity Attention (Bi-ISA) modules proposed in UCoFiA [8]. Unlike conventional linear similarity aggregation, these modules leverage a dual-softmax attention mechanism, which achieves more accurate and robust cross-modal semantic alignment. The detailed structures of the ISA and Bi-ISA modules are illustrated in Figure 3.
Figure 3.
Triplet-frame Bidirectional Interactive Similarity Attention. The architecture of the Interactive Similarity Attention (ISA) module is shown in (a,b) and forms the core component of the Bidirectional ISA (Bi-ISA) module illustrated in (c).
ISA. The ISA module is used for cross-granularity alignment. Specifically, it computes sentence–frame and video–triplet similarity scores. Its detailed structure is depicted in Figure 3a,b. Taking the similarity between the global text feature and the frame-level video feature as an example, the module first computes the initial similarity vector via a dot product:
This vector is then transformed through the following operations:
where is a learnable weight vector and denotes summation over all elements of the vector.
Bi-ISA. The Bi-ISA module is employed for same-granularity alignment. Specifically, it derives triplet–frame and word–patch similarity scores. Its core component is the ISA module. The outputs from both directional ISA computations are concatenated and weighted-summed. This enables more comprehensive bidirectional information interaction and similarity enhancement. The structure is illustrated in Figure 3c. Taking the computation of triplet–frame similarity as an example, the procedure is as follows. First, the initial similarity vector is obtained.
Subsequently, bidirectional information interaction is performed using the following formulas:
3.3. Feature Disentanglement Module
Videos inherently encode both spatial appearance and temporal dynamics through sequences of frames, whereas static images contain only spatial information. In natural language, spatial and temporal information exhibit a semantic modality separation. Spatial information is mainly carried by nouns and adjectives. These terms describe static objects, their attributes, and spatial relations. Temporal information is primarily conveyed by verbs and adverbs. They capture object motion and changes over time. However, video captions typically entangle both spatial and temporal information. This results in a spatiotemporal semantic mismatch when aligning video-derived text with static images, where temporal descriptions act as noise.
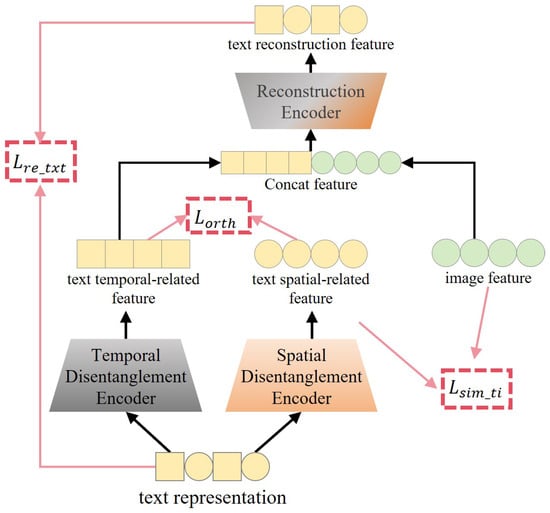
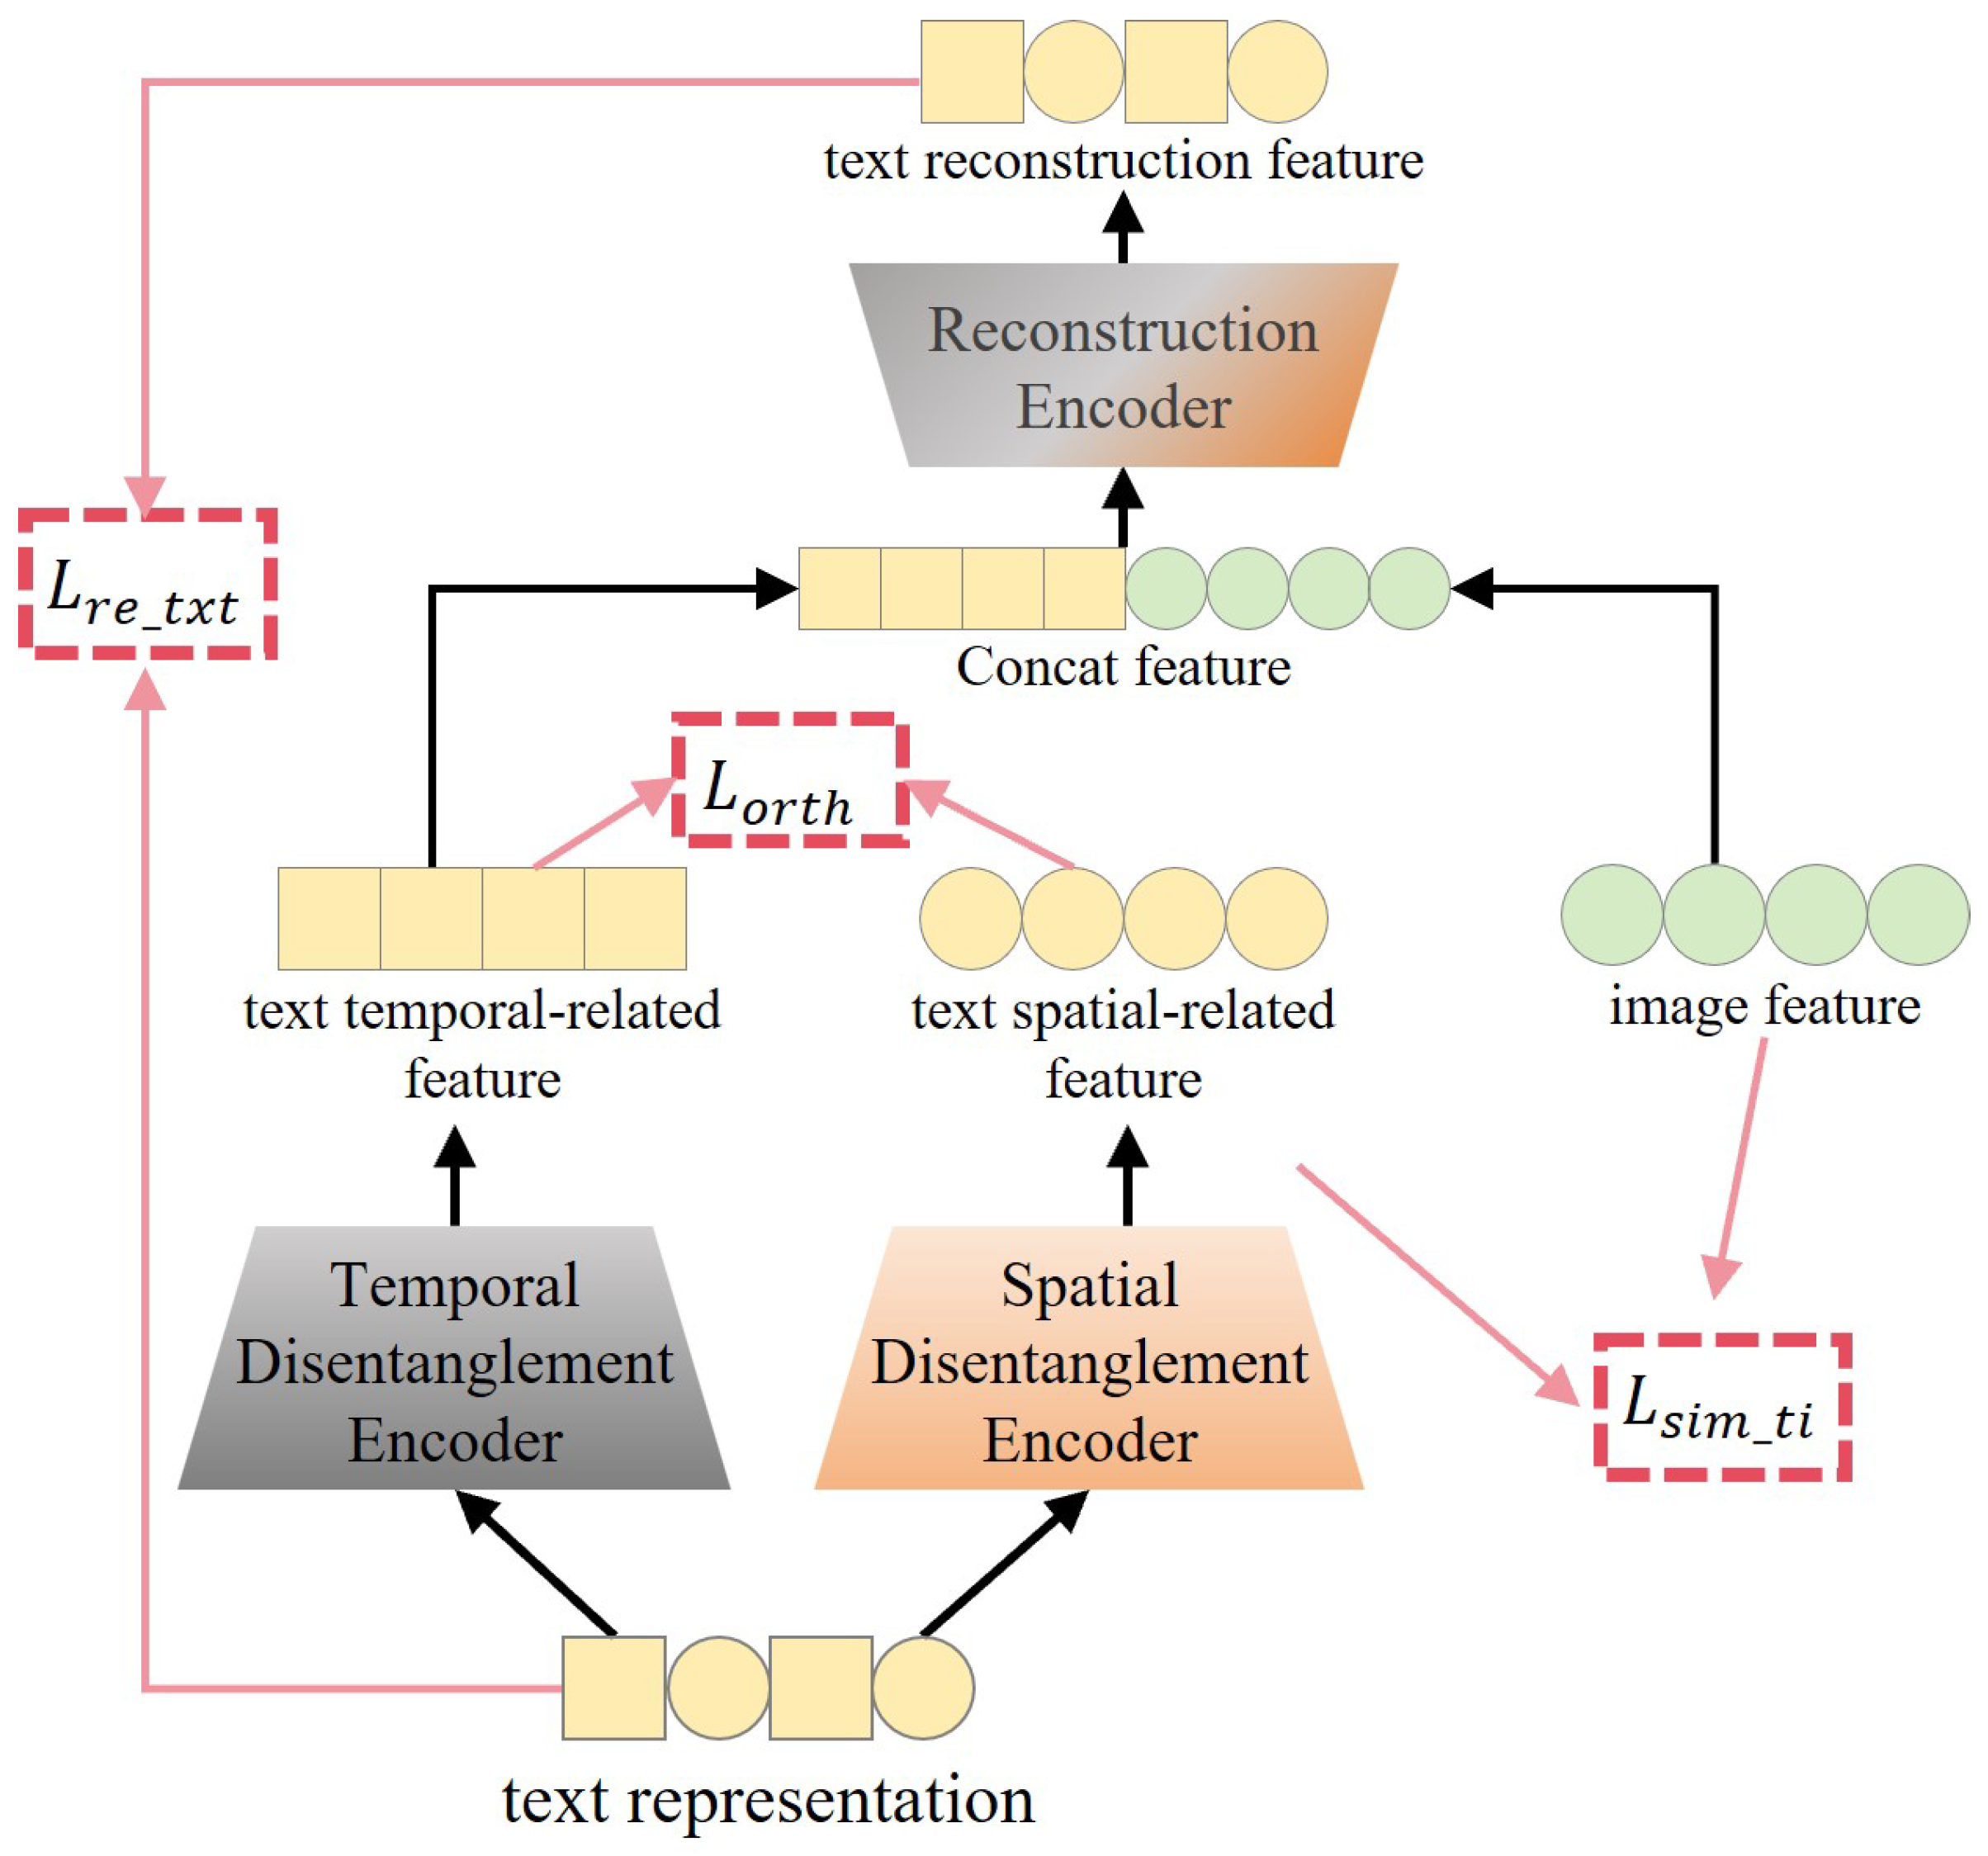
To address this issue, we propose a Feature Disentanglement Module that explicitly separates spatial and temporal semantics in textual representations. The module extracts spatial-related features for alignment with images while isolating temporal-related features to reduce interference, thereby improving cross-modal retrieval performance. The overall architecture is illustrated in Figure 4.
Figure 4.
Feature Disentanglement Module Architecture. The textual features are first fused and then processed by two separate encoders to extract text spatial feature and text temporal feature. While the spatial features are aligned with image features, the temporal features are constrained to be orthogonal to the spatial features. Finally, the original text representation is jointly reconstructed using the image features and the disentangled temporal features, ensuring the accuracy and effectiveness of the disentanglement process. (The black arrows indicate the flow of data in the model. The red arrows indicate the data used to calculate the loss).
3.3.1. Module Overview
The feature disentanglement module is inspired by MAP-IVR [11], which employs a video motion encoder and a video appearance encoder to disentangle video features into motion features and appearance features. We introduce a triple-encoder architecture for textual feature disentanglement. The module comprises a textual temporal disentanglement encoder , a textual spatial disentanglement encoder and a reconstruction encoder . Each encoder is implemented as a multi-layer perceptron (MLP) with GELU activation:
The spatial disentanglement encoder separates spatial-related features from the text, while the temporal disentanglement encoder isolates temporal-related features from the text. The reconstruction encoder ensures that the original textual information can be faithfully reconstructed from the concatenation of temporal features and image features. This design promotes effective disentanglement of spatial and temporal information. The overall architecture of the feature disentanglement module during training is illustrated in Figure 4. The detailed procedure is as follows.
3.3.2. Disentanglement
We aggregate multi-granularity textual features into a unified text representation T using element-wise max pooling:
where max denotes taking the maximum value along the first dimension. Subsequently, the text representation T is disentangled into temporal-related features and spatial-related features using the temporal disentanglement encoder and the spatial disentanglement encoder :
The primary objective of the feature-disentanglement module is to achieve precise alignment between the spatial-related text features and the image features. To this end, we introduce a spatial text–image alignment loss , which encourages the spatial-related text feature to closely match the image feature . is derived from the CLS token of the image encoder. The alignment is optimized using a sigmoid-based loss function, formulated as follows:
where B is the batch size, denotes a learnable temperature parameter, denotes the similarity score between the ith text and the jth image, is a learnable bias term, and indicates the pairwise label.
Meanwhile, to maximize the separation between temporal and spatial information, an orthogonal constraint loss is introduced. By minimizing the cosine similarity between the spatial-related feature and the temporal-related feature , this loss encourages the two feature sets to be as orthogonal as possible in the embedding space, thereby promoting effective feature disentanglement:
3.3.3. Reconstruction
To further ensure effective disentanglement, we introduce a reconstruction encoder . This component reconstructs the original text features by concatenating the temporal feature with the image feature, thereby providing a regularization signal during the training of the disentanglement modules. Specifically, the temporal-related feature and the image feature are concatenated as . This combined feature is then mapped back to the original text-feature space via to get the text reconstruction feature :
Additionally, to supervise this process, we employ a text reconstruction loss . It minimizes the discrepancy between the original unified text representation T and the reconstructed feature , formulated as follows:
where denotes L2-norm distance.
3.4. Training Objective
The framework is trained in two stages: feature learning and feature disentanglement learning.
3.4.1. Feature Learning
In the first stage, the model focuses on learning multi-granularity semantic representations and establishing accurate cross-modal alignment. We adopt the sigmoid loss proposed in SigLIP [28], which replaces the global softmax-based InfoNCE objective with a sigmoid-based formulation. This formulation alleviates the dependence on large batch sizes while maintaining effective contrastive learning. Formally, the loss is defined as:
where B is the batch size, is a learnable temperature parameter, denotes the similarity score between the ith text and the jth video, is a learnable bias term, and indicates the pairwise label.
During this stage, the model optimizes cross-modal similarity across multiple granularities, leveraging the MGSA module introduced in Section 3.2. The ISA and Bi-ISA modules further enhance alignment by modeling complex interactions between text and video representations at different levels. Specifically, alignment losses are computed for five granularity pairs: sentence–video, triplet–frame, word–patch, sentence–frame, and triplet–video. The overall training objective in this stage is formulated as:
In this stage, the feature disentanglement module is not activated. All model parameters, including the text encoder, video encoder, and the MGSA module, are jointly optimized under the supervision of the loss, .
3.4.2. Feature Disentanglement Learning
Based on the pre-trained model from the feature learning stage, we activate the feature disentanglement module to learn spatial-related and temporal-related features separately from the text representations. This stage aims to improve text–image alignment accuracy, with a particular focus on mitigating the spatiotemporal information asymmetry inherent in cross-modal retrieval.
During this stage, we freeze all feature extraction modules (text encoder, image encoder, video encoder and multi-granularity alignment module) and optimize only the disentanglement encoders and the reconstruction encoder . The training objective consists of three components: (i) the spatial text–image alignment loss enhances holistic text–image alignment; (ii) the orthogonal constraint loss maximizes separation between temporal-related and spatial-related features; and (iii) the text reconstruction loss ensures that text features are faithfully disentangled into spatial and temporal components. Their detailed formulations are provided in Section 3.3.
The overall objective for this stage is a weighted combination of these losses:
where are hyper-parameters.
Through this two-stage training design, the model not only learns rich multi-granularity semantic associations but also effectively decouples and aligns key modal features, thereby significantly improving the accuracy and robustness of cross-modal retrieval.
4. Experiments
4.1. Datasets Setup
4.1.1. Image Extraction
Existing datasets typically contain only text–video pairs and cannot directly support simultaneous text-to-image and text-to-video retrieval. To address this, we converted existing text–video datasets into a text–image–video trimodal format by selecting representative keyframes from videos. The selection was performed by computing inter-frame similarity matrices via a self-attention mechanism, as detailed below.
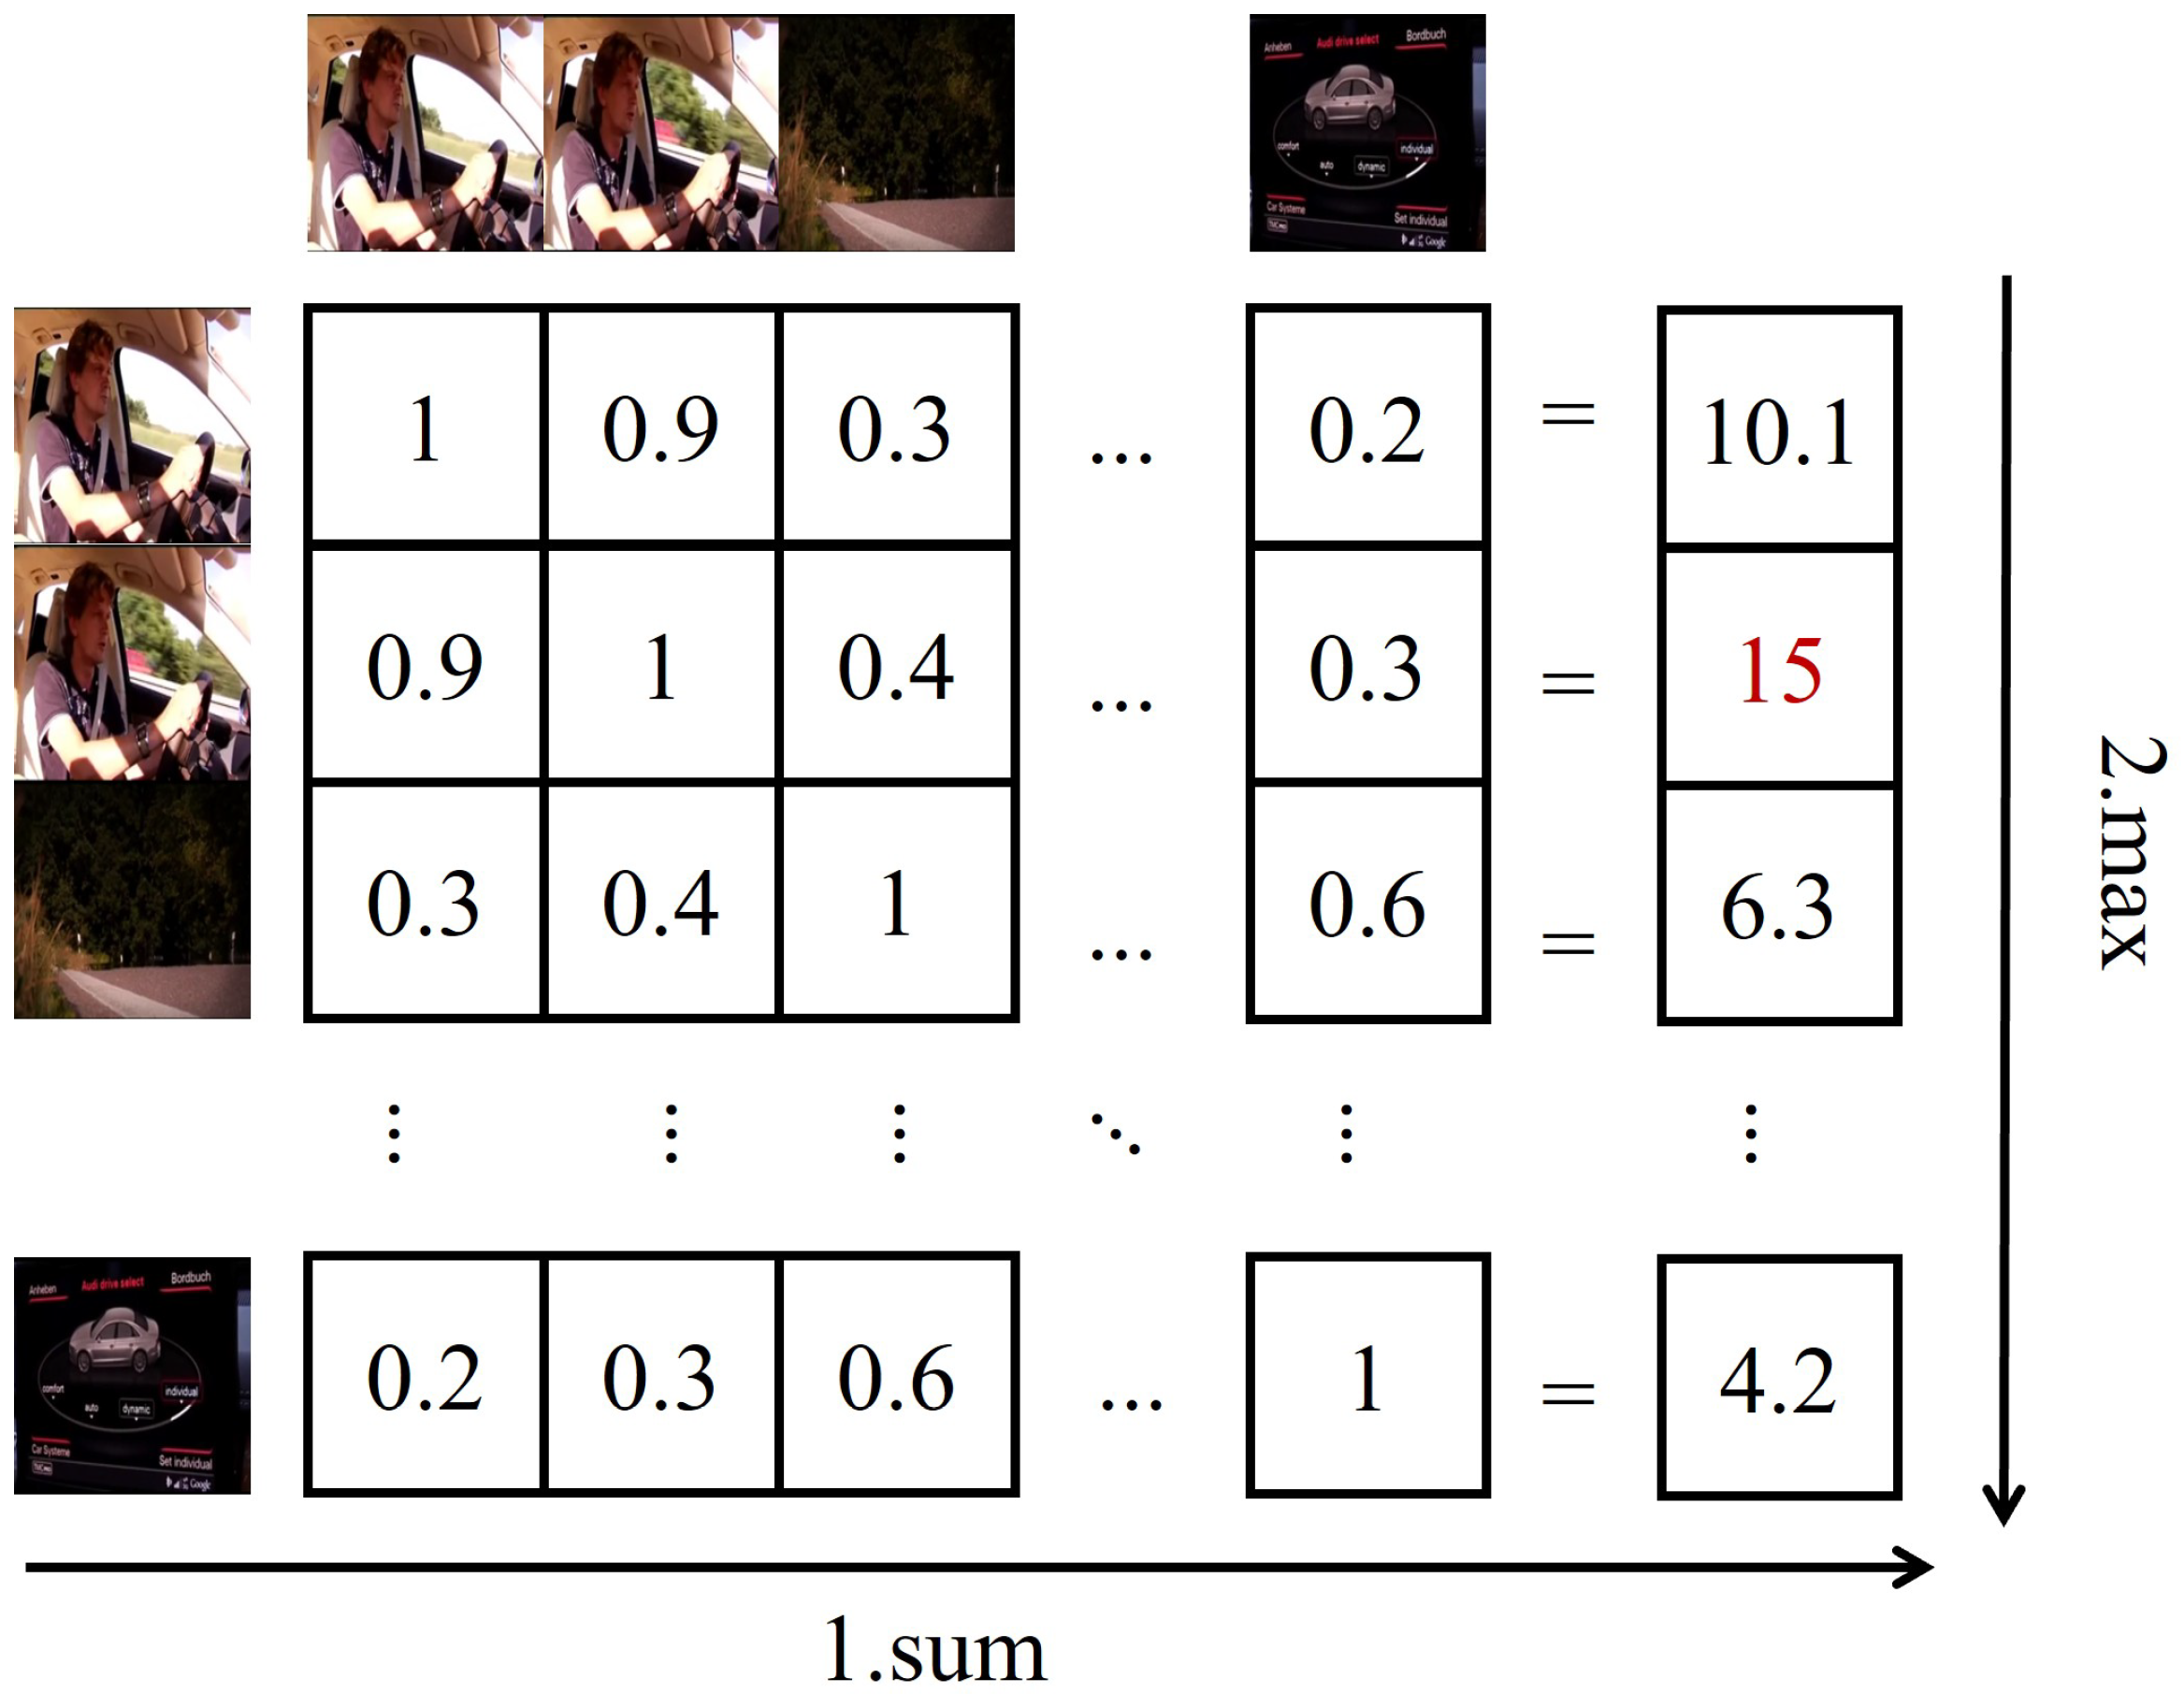
First, the cosine similarity between each pair of frame embeddings was computed as:
yielding a similarity matrix . As shown in Figure 5, the similarity scores were then summed along each row to obtain an aggregate similarity score per frame:
resulting in the score vector .
Figure 5.
Keyframe selection via similarity aggregation. After computing the pairwise similarity matrix S between frame embeddings, the similarities in each row are summed to obtain a frame-wise relevance score. The frame with the highest aggregate score is selected as the representative image (e.g., the position highlighted in red in the matrix visualization).
Finally, the frame with the highest aggregate similarity score is selected as the representative image, where
4.1.2. Datasets
MSR-VTT [29] contains 10,000 videos, each paired with 20 English captions. Following the [30,31] standard, the training set used Training-9K with 9000 videos, while the test set employed the test1k-A split from JSFusion [32].
MSVD [33] comprises 1970 YouTube videos spanning 1 to 62 s in duration, annotated with a total of 78,800 descriptions, yielding an average of approximately 40 descriptions per video. In accordance with the established CLIP4Clip protocol, the dataset was partitioned into 1200 videos for training, 100 for validation, and 670 for testing.
DiDeMo [34] includes 10,464 videos accompanied by 40,000 temporally aligned descriptions (about four per video). These descriptions are concatenated into paragraph-level captions to form video–paragraph pairs. The standard partition yielded 8395 training samples, 1065 validation samples, and 1004 test samples.
4.1.3. Evaluation Metrics
The evaluation employed standard retrieval metrics: Recall at K (R@K). Specifically, R@K calculates the proportion of queries for which the ground-truth item is retrieved among the top K results (K = 1, 5, 10). Consequently, better performance corresponds to higher R@K values.
4.2. Experimental Setup
We adopted X-CLIP as the baseline method. The framework was implemented in PyTorch, and all experiments were conducted on a single NVIDIA GeForce RTX 4090 24 GB GPU. Both the text and image encoders were initialized with publicly released CLIP checkpoints. The pre-trained CLIP model was fine-tuned with a learning rate of , while the remaining components were trained with a learning rate of . Optimization was performed using the Adam optimizer with a cosine learning rate scheduler. The embedding dimensions for text, video, and image were uniformly set to 512, consistent with the dimensions of the spatial and temporal features in the text decomposition module. In submodule configurations, the number of layers l in the temporal encoder and the top-K parameter in the patch selection module were set to four and six, respectively. For MSR-VTT and MSVD, we sampled 12 frames per video, set the maximum text length per independent caption to 32, and trained for five epochs with a batch size of 64. For DiDeMo, we used 64 frames per video, merged the five captions into a single paragraph (maximum length 64), and trained for 10 epochs with a batch size of 16.
4.3. Comparison to State-of-the-Art Models
We selected several state-of-the-art methods as comparative baselines, including CLIP4Clip [13], X-CLIP [6], EERCF [35], TS2-Net [36], and UCoFiA [8]. Among them, CLIP4Clip, X-CLIP, and EERCF directly adopt ViT-based architectures for visual feature extraction, while TS2-Net and UCoFiA enhance the ViT structure by incorporating token shifting during the visual feature extraction stage, which enables inter-frame token interaction. However, these methods are designed solely for text-to-video retrieval and do not simultaneously perform text-to-image retrieval.
To adapt them for image retrieval, we adopted the following strategies:
- For CLIP4Clip, X-CLIP, and EERCF, we extracted the [CLS] token from the ViT encoder as the image representation and computed its similarity with the text feature.;
- For TS2-Net and UCoFiA, which require a sequence of frames (e.g., 12 frames) as input and cannot process a single image directly, we constructed a pseudo-video by repeating the single image 12 times. This frame sequence was fed into the video encoder to obtain the image feature, which was then compared with the text feature.
To ensure a fair and reliable comparison, we re-implemented all baseline methods using their officially released code and followed the training strategies described in the respective papers. Under the experimental environment specified in Section 4.2, we retrained these compared methods on the MSR-VTT, MSVD, and DiDeMo datasets.
On the MSR-VTT dataset, Table 1 presents the results of UniTriM on both text–video retrieval and text–image retrieval tasks. For text–video retrieval, UniTriM achieves in terms of R@1, which is 0.6 percentage points higher than X-CLIP’s . Although this value is lower than that of EERCF, it still attains a second-best performance. In the R@5 and R@10 metrics, UniTriM also demonstrates clear advantages, reaching and respectively, outperforming all compared baselines. Specifically, R@5 improves by 2.2 percentage points over X-CLIP, and R@10 improves by 1.6 percentage points. For text–image retrieval, UniTriM achieves , , and on R@1, R@5, and R@10 respectively, surpassing all competing methods. Notably, on R@1, UniTriM exceeds X-CLIP by 5.5 percentage points, which strongly validates the effectiveness of the proposed multi-granularity semantic fusion and feature disentanglement modules in aligning text with static images across modalities.
Table 1.
Comparison of different methods on MSRVTT. (Bold values indicate the best performance in each column).
On the MSVD dataset, UniTriM also demonstrates superior performance. As shown in Table 2, for text–video retrieval, UniTriM achieves on R@1, which is 0.9 percentage points higher than X-CLIP’s , and attains the highest score among all methods on R@10, exceeding X-CLIP by 0.8 percentage points. For text–image retrieval, UniTriM exhibits an even more pronounced advantage, reaching on R@1, a substantial improvement of 6.0 percentage points over X-CLIP’s . It also leads on R@10 with a score of . These results further validate the robustness and generalization ability of the proposed model across datasets of different scales.
Table 2.
Comparison of different methods on MSVD. (Bold values indicate the best performance in each column).
On the DiDeMo dataset, which contains longer videos and paragraph-level text descriptions and thus presents a greater challenge, UniTriM still maintains strong performance. As shown in Table 3, for text–video retrieval, UniTriM achieves on R@1, representing an improvement of 1.3 percentage points over X-CLIP’s . It also delivers the best results on R@5 and R@10, reaching and respectively. For text–image retrieval, UniTriM attains on R@1, outperforming X-CLIP’s by 4.0 percentage points. It likewise surpasses all other methods on R@5 and R@10, with scores of and respectively.
Table 3.
Comparison of different methods on DiDeMo. (Bold values indicate the best performance in each column).
To comprehensively evaluate the model’s practicality, we compare the number of parameters and inference speed of our method against other approaches in Table 4. As can be seen, our method has a higher parameter count and requires more inference time than the comparison methods. We attribute the increase in parameters primarily to the encoders within our feature-disentanglement module. This is a trade-off we find acceptable given the resulting performance gains. Regarding inference speed, our method is slower than CLIP4Clip, X-CLIP, and EERCF. This is due to the additional computation introduced by the fine-grained alignment. However, it is faster than TS2-Net and UCoFiA because TS2-Net and UCoFiA cannot process images directly. They must expand each image into a video for computation, which significantly increases their computational load.
Table 4.
Comparison of model parameters and inference speed.
4.4. Ablation Studies
To evaluate the effectiveness of each module, we conducted ablation studies on the MSR-VTT dataset. First, we conducted an ablation study on the alignments at different granularities in the MGSA mechanism. We conducted experiments by incrementally adding each proposed component. The results are summarized in Table 5. When only coarse-grained alignment between text and video is used, the model achieves , , and on R@1, R@5, and R@10, respectively. After incorporating all five granularity-level alignments, the R@1 score improves by 3.5 percentage points to , R@5 increases by 3.0 percentage points to , and R@10 rises by 3.5 percentage points to . These results demonstrate the importance of multi-granularity alignment in capturing fine-grained vision–language correspondences. The multi-granularity alignment mechanism effectively integrates semantic information from different hierarchical levels, leading to significant performance gains.
Table 5.
Comparison of different granularity alignments in the MGSA mechanism. (Bold values indicate the best performance in each column. The symbol “√” denotes used, and “-” denotes not used).
As shown in Table 6, the experiments primarily assessed the contribution of the disentanglement module. No-Disentangle denotes the approach that directly employs the textual feature for text-to-image retrieval, where the textual feature is obtained by summing the sentence-level, triplet-level, and word-level representations without processing through the spatial disentanglement encoder. For the text-to-image retrieval task, the model equipped with the spatial disentangler achieves superior performance. When No-Disentangle is used, the model achieves R@1, R@5, and R@10 scores of , , and , respectively, on the text–image retrieval task. With the introduction of the spatial disentangler, these metrics improve to , , and , with R@1 increasing by 2.6 percentage points. This demonstrates that the spatial disentangler can effectively separate features from non-critical spatial interference in images, enabling the model to focus more on core visual content during the semantic matching process between text and static images, thereby significantly enhancing retrieval accuracy.
Table 6.
Comparison of disentanglement on MSRVTT. (Bold values indicate the best performance in each column).
In addition, we performed an ablation study on the parameter k in the patch selection module. The results are shown in Table 7 above. The optimal performance was achieved when k = 8. In the experiments, we evaluated three different numbers of selected patches: k = 4, k = 6, and k = 8. In terms of the R@1 metric for the text–video retrieval task, the model achieved when k = 4, improved to when k = 6, and further reached when k = 8, marking a gain of 0.1 percentage points over k = 6. For the R@5 metric, the results were at k = 4, at k = 6, and at k = 8, an improvement of 0.4 percentage points over k = 6. Overall, as the value of k increased from four to eight, the model showed a gradual improvement in both R@1 and R@5 metrics.
Table 7.
Comparison of the k value in the patch selection module. (Bold values indicate the best performance in each column).
Additionally, we conducted an ablation study on the weighting parameters and in the loss function during the feature disentanglement learning stage. Here, controls the strength of the reconstruction constraint, while regulates the orthogonality constraint. We evaluated , and the results are shown in Table 8. To better illustrate the results, we introduce the Rsum evaluation metric, defined as the sum of R@1, R@5, and R@10 in the text–image retrieval task. This metric provides a comprehensive measure of the model’s overall retrieval performance. We observe that the highest Rsum score of 145.7 was achieved when and .
Table 8.
Impact of different and in the feature disentanglement learning stage. (Bold values indicate the best performance in each column).
4.5. Visualization
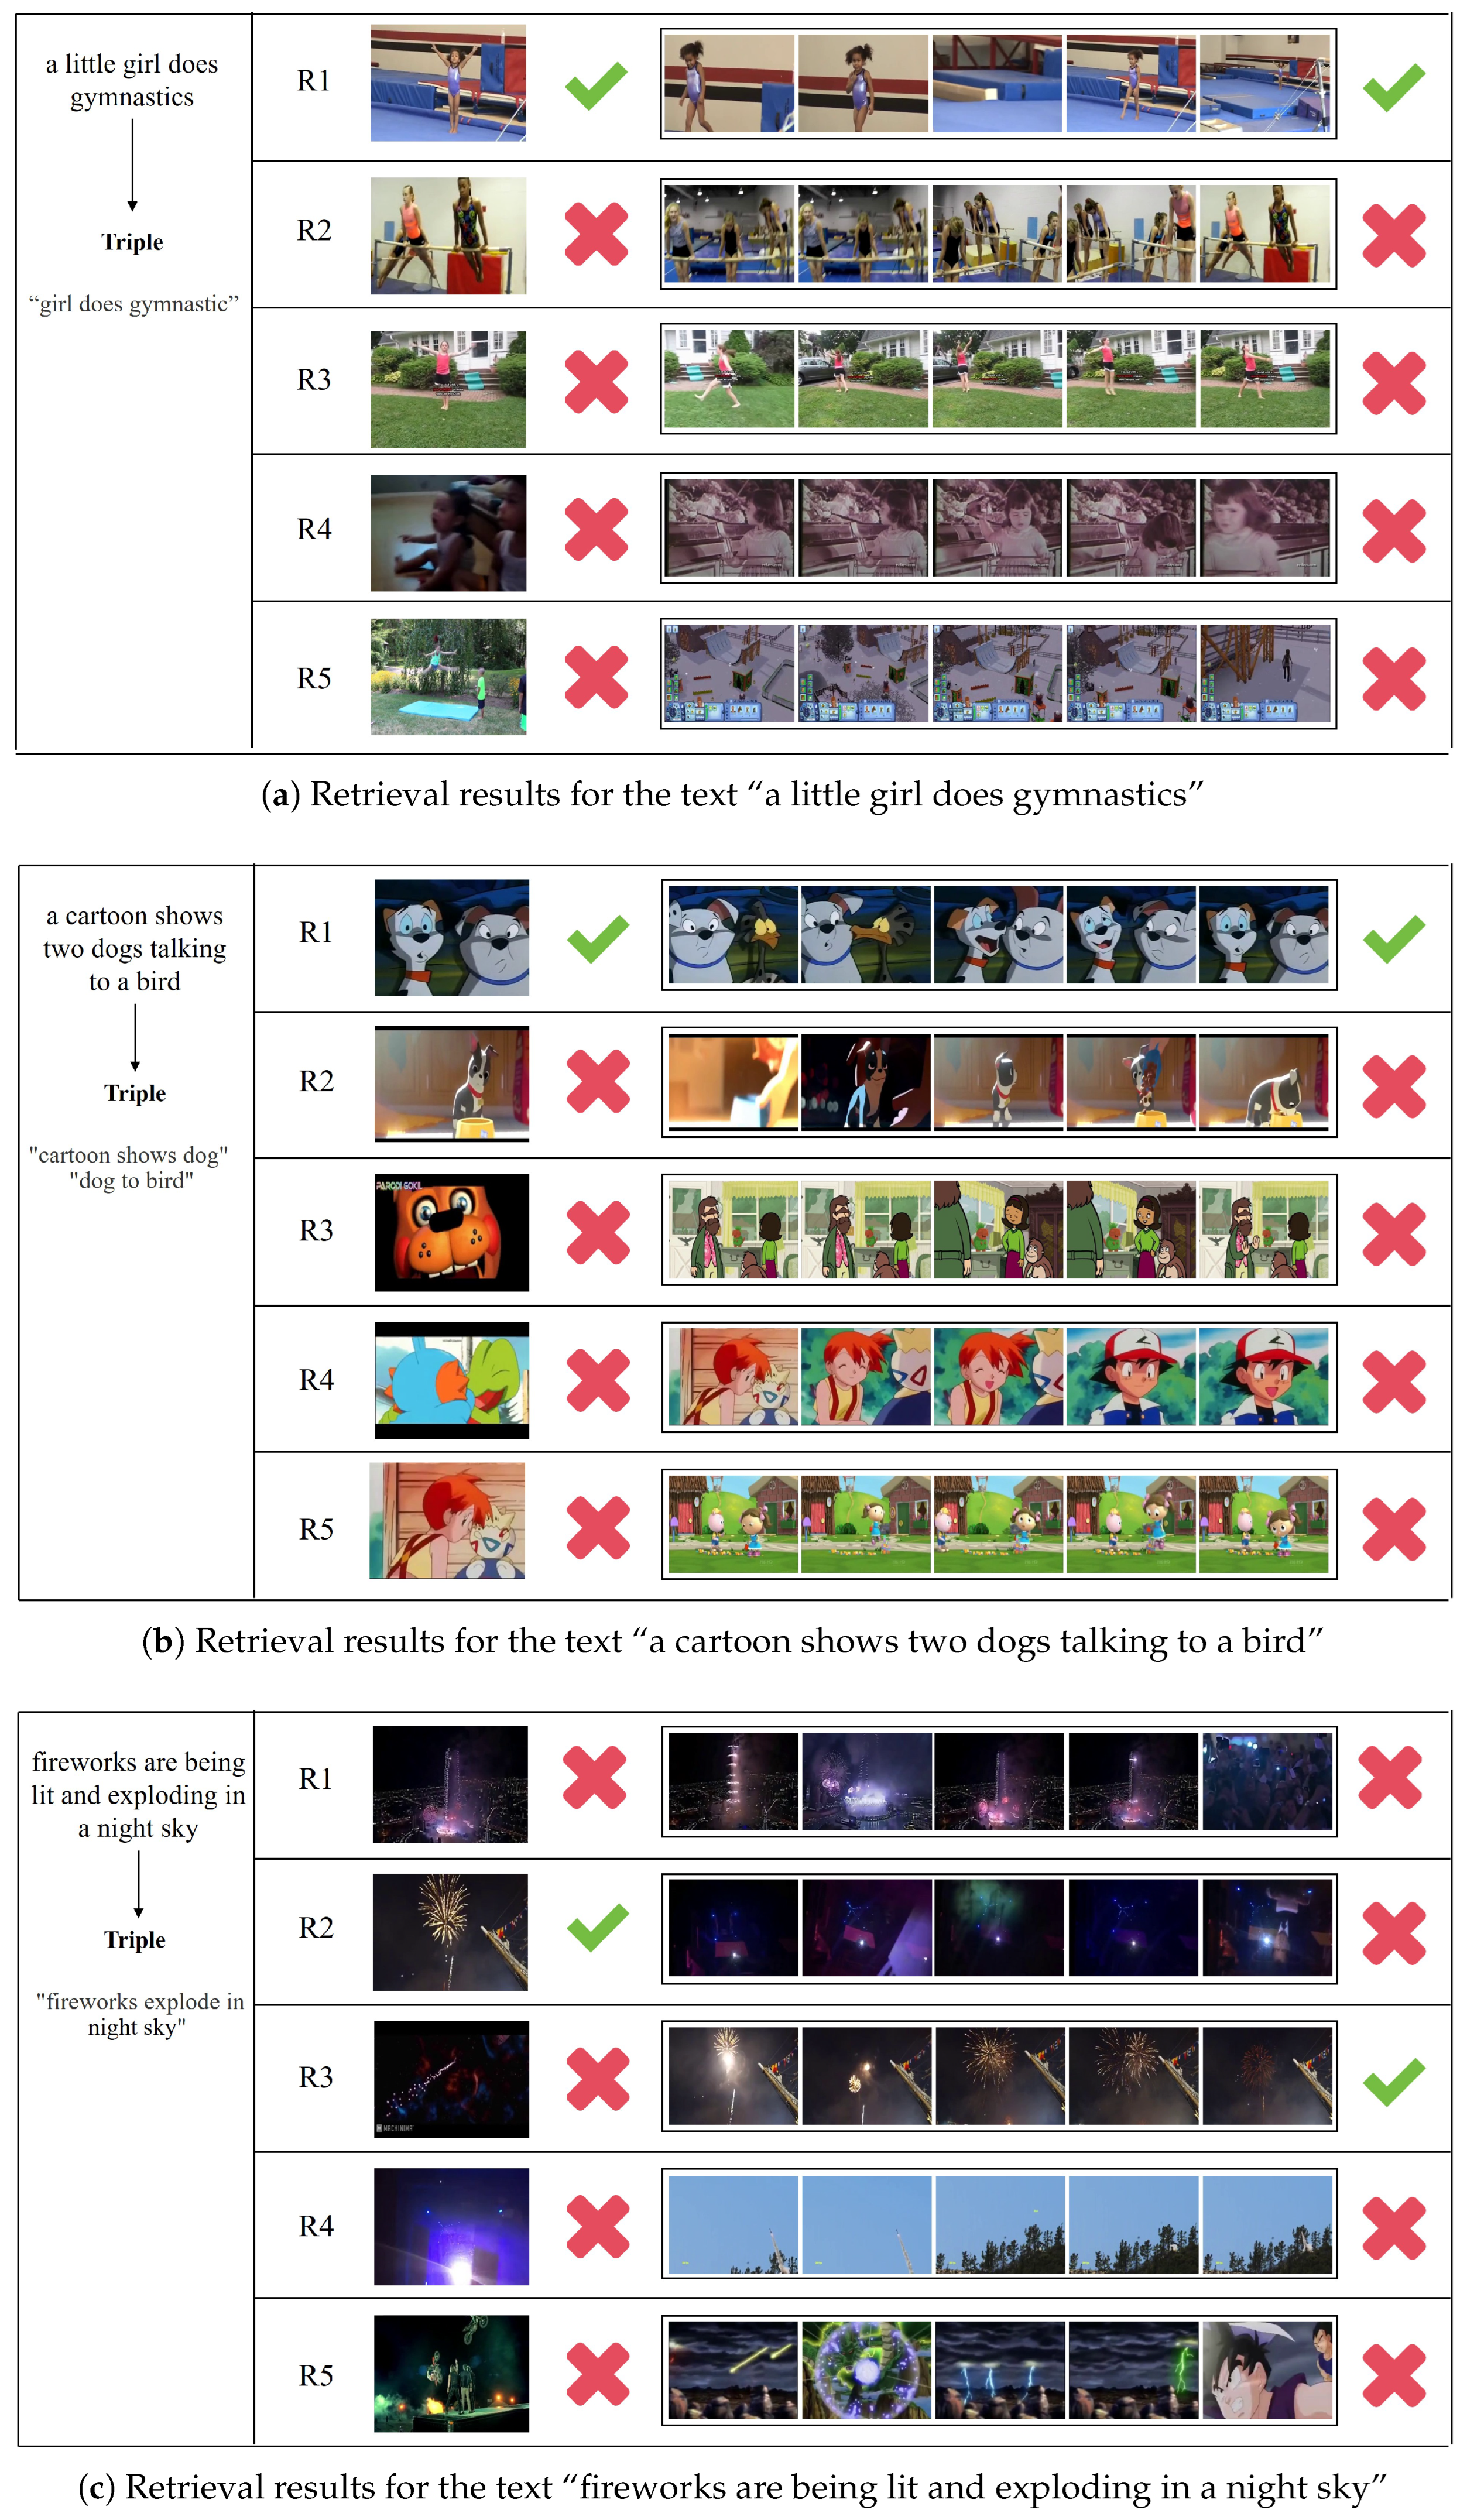
To intuitively evaluate cross-modal semantic alignment, we show qualitative results on text–image–video retrieval in Figure 6. The bottom left shows the extracted triplets from the sentence, the middle displays the top-five retrieved images ranked by similarity, and the right shows keyframes from the top-five retrieved videos. Green checkmarks indicate positive results, and red crosses indicate negative ones. The test set was constructed with a one-to-one mapping, meaning each query text was associated with only one ground-truth video.
Figure 6.
The results of image and video retrieval for a given text query. The top-five retrieval matches are shown. Images are displayed in the middle and videos on the right. Green checkmarks (√) denote positive samples, and red crosses (×) denote negative samples.
As shown in Figure 6a for the query “a little girl does gymnastics,” our model first retrieves scenes related to the triplet “girl does gymnastics” or those containing girls. The modifiers “a” and “little” then enhance retrieval precision. This demonstrates the effectiveness of our fine-grained cross-modal retrieval approach. Figure 6b shows that for the query “a cartoon shows two dogs talking to a bird,” our model primarily retrieves cartoon-related scenes and then further aligns them through words such as “dog” and “bird.” In Figure 6c, we analyze the retrieval results for the query “fireworks are being lit and exploding in a night sky.” Our model tends to return scenes associated with “fireworks” and “night sky.” However, because the dataset contains visually similar content, retrieval errors occur, reflecting a certain bias in the model’s predictions.
4.6. Generalization
We further validated the framework’s generalization ability through zero-shot experiments. The results are presented in Table 9. Specifically, we trained UniTriM on the MSR-VTT dataset and then evaluated it directly on MSVD and DiDeMo without any fine-tuning. Compared to standard CLIP-based baselines, UniTriM achieved superior zero-shot performance. It improved R@1 by on MSVD and on DiDeMo. This suggests that the multi-granularity alignment module enables the model to learn more general semantic correspondences. Therefore, it transfers better to unseen data distributions and avoids overfitting to the training set. Meanwhile, UniTriM adopts a dual-stream architecture, allowing visual features to be pre-computed offline and stored as embeddings. In real-world social media retrieval scenarios, only text query encoding and similarity computation are required at inference time.
Table 9.
Zero-shot performance on MSVD and DiDeMo.
4.7. Comprehensive Result Analysis and Discussion
To provide deeper insights into UniTriM’s results, we conducted supplementary analyses on performance improvements across tasks and datasets. Firstly, as shown in Table 1, Table 2 and Table 3, UniTriM achieves significantly higher average improvements on image retrieval tasks compared to video retrieval. We attribute this phenomenon to two main factors: 1. Targeted module design: The feature disentanglement module is specifically designed to align spatial semantics in text with static images. This design directly addresses the core requirements of image retrieval, thus yielding more substantial gains. 2. Differences in baseline saturation: The video retrieval field has witnessed extensive research, with baselines already operating at a relatively high performance level, leaving limited room for improvement. In contrast, image–video joint retrieval is a more emerging task where existing methods are mostly simple adaptations of video models; therefore, UniTriM’s targeted design brings more significant breakthroughs.
Secondly, we analyzed UniTriM’s performance variations across different video datasets. On MSRVTT, performance improvements are relatively modest. We believe this is because the video annotations are relatively concise and the video duration is short, leaving limited room for improvement. On MSVD, due to minimal scene changes and high background consistency across clips, the model encounters less interference during feature extraction. Additionally, individual frames contain richer semantic information, leading to better retrieval performance than on MSRVTT. For the DiDeMo dataset, its paragraph-level descriptions provide more learnable semantic triplets for the model and enhance attention to core vocabulary. Meanwhile, the denser frame sampling strategy offers more detailed information for temporal modeling, collectively contributing to improved retrieval accuracy. These analyses validate the effectiveness of UniTriM’s design choices and highlight how dataset characteristics influence multimodal retrieval performance.
5. Discussion
In this section, some limitations of our proposed approach are discussed. First of all, although the multi-granularity alignment and feature disentanglement modules improve retrieval accuracy, they also increase computational overhead. In the current framework, the model is required to simultaneously process multi-level similarity computations leading to reduced efficiency in both training and inference. To address this, future work will investigate incorporating knowledge distillation or lightweight attention mechanisms to improve inference speed while maintaining performance. This can enhance the framework’s suitability for real-time retrieval in practical self-media content creation platforms. Secondly, although the proposed self-attention-based keyframe selection method effectively constructs text–image–video triplets, its quality remains highly dependent on the accuracy of the original video descriptions. For videos with ambiguous descriptions or weak alignment with visual content, the selected keyframes may not adequately represent the core semantics of the video. Future research could explore the construction of multimodal datasets or leverage weakly supervised learning for pre-training on larger and more diverse datasets, thereby improving the model’s generalization capability.
6. Conclusions
This paper proposed the UniTriM framework, a unified architecture specifically designed to address the demand for simultaneous image and video retrieval from a single textual query in social media content creation scenarios. To overcome the scarcity of text–image–video triplet data, we developed a self-attention-based keyframe selection algorithm that transformed existing text–video datasets into a structured triplet format. Meanwhile, a multi-granularity similarity alignment module was constructed to capture semantic correspondences across patch–frame–video and word–triplet–sentence structures through joint optimization of intra- and cross-granularity alignments. To mitigate the spatiotemporal information imbalance inherent in pairing static images with video-derived text, we introduced a feature disentanglement module that explicitly separated and aligned spatial features from text with image representations. Extensive experiments on three benchmark datasets MSR-VTT, MSVD, and DiDeMo demonstrated the effectiveness of UniTriM. Results showed that our framework not only achieved competitive text–video retrieval performance but also significantly improved text–image retrieval accuracy. The framework successfully builds a unified multimodal search system with strong practicality and scalability for social media content creation. Future research will focus on improving computational efficiency and extending the framework to more diverse multimodal scenarios.
Author Contributions
Conceptualization, Y.W., Y.H. and Y.Y.; methodology, Y.W.; software, Y.W.; validation, Y.W., Y.Y. and Y.H.; formal analysis, Y.W.; investigation, Y.W.; resources, Y.W.; data curation, Y.W.; writing—original draft preparation, Y.W.; writing—review and editing, Y.W., Y.H., Y.Y. and W.Z.; visualization, Y.W.; supervision, Y.Y. and Y.H.; project administration, W.Z.; funding acquisition, W.Z. All authors have read and agreed to the published version of the manuscript.
Funding
This work was supported by Beijing Municipal Radio and Television Bureau under Grant No. ZW14144 (Research and Application Demonstration of UHD Lightweight Cloud Production and Intelligent Service Platform).
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The MSR-VTT, MSVD, and DiDeMo datasets used in this study are publicly available from their official websites.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Jin, Y.; Li, Y.; Pan, J.; Lyu, Y.; Zhou, Y.; Wang, Y.; Zhang, J.; Huang, S.; Huang, F.; Si, L. Mm-SoC:Benchmarking Multimodal Large Language Models in Social Media Platforms. In Proceedings of the Findings of the Association for Computational Linguistics: ACL 2024, Bangkok, Thailand, 11–16 August 2024; pp. 1234–1245. [Google Scholar]
- Li, C.; Xu, H.; Tian, J.; Wang, W.; Yan, M.; Bi, B.; Ye, J.; Chen, H.; Xu, G.; Cao, Z.; et al. mPLUG: Effective and Efficient Vision-Language Learning by Cross-Modal Skip-Connections. In Proceedings of the 2022 Conference on Empirical Methods in Natural Language Processing (EMNLP), Abu Dhabi, United Arab Emirates, 7–11 December 2022; pp. 7241–7259. [Google Scholar]
- Li, J.; Li, D.; Xiong, C.; Hoi, S. BLIP: Bootstrapping Language-Image Pre-training for Unified Vision-Language Understanding and Generation. In Proceedings of the 39th International Conference on Machine Learning (ICML), Baltimore, MD, USA, 17–23 July 2022; Volume 162, pp. 12888–12900. [Google Scholar]
- Wang, J.; Chen, D.; Wu, Z.; Luo, C.; Tang, J.; Yu, X.; Yuan, Z.; Xie, W.; Wang, L.; Shen, Y.; et al. OmniVL: One Foundation Model for Image-Language and Video-Language Tasks. In Advances in Neural Information Processing Systems 35 (NeurIPS 2022); Curran Associates Inc.: Red Hook, NY, USA, 2022; pp. 5696–5710. [Google Scholar]
- Xu, H.; Ye, Q.; Yan, M.; Yuen, J.; Zhang, J.; Huang, F.; Huang, J.; Zhou, J.; Si, L. mPLUG-2: A Modularized Multi-Modal Foundation Model Across Text, Image and Video. In Proceedings of the 40th International Conference on Machine Learning (ICML), Honolulu, HI, USA, 23–29 July 2023; pp. 38728–38748. [Google Scholar]
- Ma, Y.; Xu, G.; Sun, X.; Yan, M.; Zhang, J.; Ji, R. X-CLIP: End-to-End Multi-grained Contrastive Learning for Video-Text Retrieval. In Proceedings of the 30th ACM International Conference on Multimedia (MM’22), Lisboa, Portugal, 10–14 October 2022; pp. 638–647. [Google Scholar]
- Jiang, J.; Min, S.; Kong, W.; Wang, H.; Li, Z.; Liu, W. Tencent Text-Video Retrieval: Hierarchical Cross-Modal Interactions with Multi-Level Representations. IEEE Access 2022, 10, 296–307. [Google Scholar] [CrossRef] [Scilit]
- Wang, Z.; Sung, Y.-L.; Cheng, F.; Bertasius, G.; Bansal, M. Unified Coarse-to-Fine Alignment for Video-Text Retrieval. In Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), Paris, France, 2–6 October 2023; pp. 2816–2827. [Google Scholar]
- Jiao, L.; Ma, M.; He, P.; Geng, X.; Liu, X.; Liu, F.; Ma, W.; Yang, S.; Hou, B.; Tang, X. Brain-Inspired Learning, Perception, and Cognition: A Comprehensive Review. IEEE Trans. Neural Netw. Learn. Syst. 2024, 36, 5921–5941. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Jiao, L.; Huang, Z.; Lu, X.; Liu, X.; Yang, Y.; Zhao, J.; Zhang, J.; Hou, B.; Yang, S.; Liu, F.; et al. Brain-Inspired Remote Sensing Foundation Models and Open Problems: A Comprehensive Survey. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2023, 16, 10084–10120. [Google Scholar] [CrossRef] [Scilit]
- Liu, L.; Li, J.; Niu, L.; Wang, H.; Zhang, C. Activity Image-to-Video Retrieval by Disentangling Appearance and Motion. In Proceedings of the 35th AAAI Conference on Artificial Intelligence (AAAI-21), Virtual Event, 2–9 February 2021; Volume 35, pp. 2145–2153. [Google Scholar]
- Zhang, K.; Li, J.; Li, Z.; Zhang, J. Composed Multi-Modal Retrieval: A Survey of Approaches and Applications. arXiv 2025, arXiv:2503.01334. [Google Scholar] [CrossRef] [Scilit]
- Han, Z.; Azman, A.B.; Mustaffa, M.R.B.; Khalid, F.B. Cross-modal retrieval: A review of methodologies, datasets, and future perspectives. IEEE Access 2024, 12, 115716–115741. [Google Scholar] [CrossRef] [Scilit]
- Radford, A.; Kim, J.W.; Hallacy, C.; Ramesh, A.; Goh, G.; Agarwal, S.; Sastry, G.; Askell, A.; Mishkin, P.; Clark, J.; et al. Learning Transferable Visual Models from Natural Language Supervision. In Proceedings of the 38th International Conference on Machine Learning (ICML), Virtual Event, 18–24 July 2021; pp. 8748–8763. [Google Scholar]
- Luo, H.; Ji, L.; Zhong, M.; Chen, Y.; Lei, W.; Duan, N.; Li, T. CLIP4Clip: An Empirical Study of CLIP for End to End Video Clip Retrieval and Captioning. Neurocomputing 2022, 508, 293–304. [Google Scholar] [CrossRef] [Scilit]
- Fang, H.; Xiong, P.; Xu, L.; Luo, W. Transferring Image-CLIP to Video-Text Retrieval via Temporal Relations. IEEE Trans. Multimed. 2023, 25, 7772–7785. [Google Scholar] [CrossRef] [Scilit]
- Xu, H.; Ghosh, G.; Huang, P.-Y.; Okhonko, D.; Aghajanyan, A.; Metze, F.; Zettlemoyer, L.; Feichtenhofer, C. VideoCLIP: Contrastive Pre-training for Zero-Shot Video-Text Understanding. arXiv 2021, arXiv:2109.14084. [Google Scholar]
- Wang, M.; Xing, J.; Mei, J.; Liu, Y.; Jiang, Y. ActionCLIP: Adapting Language-Image Pretrained Models for Video Action Recognition. IEEE Trans. Neural Netw. Learn. Syst. 2025, 36, 625–637. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wu, P.; He, X.; Tang, M.; Lv, Y.; Liu, J. HANet: Hierarchical Alignment Networks for Video-Text Retrieval. In Proceedings of the 29th ACM International Conference on Multimedia (MM ’21), Virtual Event & Chengdu, China, 20–24 October 2021; pp. 5277–5285. [Google Scholar]
- Wang, H.; Liu, F.; Jiao, L.; Wang, J.; Li, S.; Li, L.; Chen, P.; Liu, X.; Ma, W. Multi-Level Vision Language Interaction Learning for Cross-Modal Retrieval. Inf. Fusion 2026, 126, 103481. [Google Scholar] [CrossRef] [Scilit]
- Jing, X.; Yang, G.; Chu, J. TC-MGC: Text-Conditioned Multi-Grained Contrastive Learning for Text-Video Retrieval. Inf. Fusion 2025, 114, 103235. [Google Scholar] [CrossRef] [Scilit]
- Guo, J.; Lan, S.; Song, B.; Wang, M. Video-Text Retrieval Based on Multi-Grained Hierarchical Aggregation and Semantic Similarity Optimization. Neurocomputing 2025, 630, 128518. [Google Scholar] [CrossRef] [Scilit]
- Vowels, M.J.; Camgoz, N.C.; Bowden, R. VDSM: Unsupervised Video Disentanglement with State-Space Modeling and Deep Mixtures of Experts. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Nashville, TN, USA, 20–25 June 2021; pp. 8176–8186. [Google Scholar]
- Bae, K.; Ahn, G.; Kim, Y.; Kim, Y.; Yang, H.-S. DEVIAS: Learning Disentangled Video Representations of Action and Scene. In Proceedings of the 19th European Conference on Computer Vision (ECCV 2025), Melbourne, Australia, 23–27 November 2025; Springer: Cham, Switzerland, 2025; pp. 431–448. [Google Scholar]
- Hu, T.; Zhang, J.; Yi, R.; Zha, H.; Liu, Y.; Feng, J. COMD: Training-Free Video Motion Transfer with Camera-Object Motion Disentanglement. In Proceedings of the 32nd ACM International Conference on Multimedia (MM’24), Melbourne, Australia, 28 October–1 November 2024; pp. 3459–3468. [Google Scholar]
- Wang, Q.; Zhang, Y.; Zheng, Y.; Yan, X.; Wang, J.; Wang, S.; Sun, M. Disentangled Representation Learning for Text-Video Retrieval. arXiv 2022, arXiv:2203.07111. [Google Scholar] [CrossRef] [Scilit]
- Schuster, S.; Krishna, R.; Chang, A.; Fei-Fei, L.; Manning, C.D. Generating Semantically Precise Scene Graphs from Textual Descriptions for Improved Image Retrieval. In Proceedings of the 4th Workshop on Vision and Language (VL’15), Lisbon, Portugal, 18 September 2015; pp. 70–80. [Google Scholar]
- Zhai, X.; Mustafa, B.; Kolesnikov, A.; Beyer, L. Sigmoid Loss for Language Image Pre-Training. In Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), Paris, France, 2–6 October 2023; pp. 11975–11986. [Google Scholar]
- Xu, J.; Mei, T.; Yao, T.; Rui, Y. MSR-VTT: A Large Video Description Dataset for Bridging Video and Language. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Las Vegas, NV, USA, 27–30 June 2016; pp. 5288–5296. [Google Scholar]
- Miech, A.; Zhukov, D.; Alayrac, J.-B.; Tapaswi, M.; Laptev, I.; Sivic, J. HowTo100M: Learning a Text-Video Embedding by Watching Hundred Million Narrated Video Clips. In Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), Seoul, Republic of Korea, 27 October–2 November 2019; pp. 2630–2640. [Google Scholar]
- Gabeur, V.; Sun, C.; Alahari, K.; Schmid, C. Multi-Modal Transformer for Video Retrieval. In Proceedings of the 16th European Conference on Computer Vision (ECCV 2020), Glasgow, UK, 23–28 August 2020; Springer: Cham, Switzerland, 2020; pp. 1707–1720. [Google Scholar]
- Yu, Y.; Kim, J.; Kim, G. A Joint Sequence Fusion Model for Video Question Answering and Retrieval. In Proceedings of the 15th European Conference on Computer Vision (ECCV 2018), Munich, Germany, 8–14 September 2018; pp. 487–503. [Google Scholar]
- Chen, D.; Dolan, W. Collecting Highly Parallel Data for Paraphrase Evaluation. In Proceedings of the 49th Annual Meeting of the Association for Computational Linguistics: Human Language Technologies (ACL-HLT 2011), Portland, OR, USA, 19–24 June 2011; pp. 190–200. [Google Scholar]
- Hendricks, L.A.; Wang, O.; Shechtman, E.; Sivic, J.; Darrell, T.; Russell, B. Localizing Moments in Video with Natural Language. In Proceedings of the IEEE International Conference on Computer Vision (ICCV), Venice, Italy, 22–29 October 2017; pp. 5803–5812. [Google Scholar]
- Tian, K.; Cheng, Y.; Liu, Y.; Hou, X.; Chen, Q.; Li, H. Towards Efficient and Effective Text-to-Video Retrieval with Coarse-to-Fine Visual Representation Learning. In Proceedings of the 38th AAAI Conference on Artificial Intelligence (AAAI-24), Vancouver, BC, Canada, 20–27 February 2024; Volume 38, pp. 5207–5214. [Google Scholar]
- Liu, Y.; Xiong, P.; Xu, L.; Cao, S.; Jin, Q. TS2-Net: Token Shift and Selection Transformer for Text-Video Retrieval. In Proceedings of the 17th European Conference on Computer Vision (ECCV 2022), Tel Aviv, Israel, 23–27 October 2022; pp. 319–335. [Google Scholar]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.