


Abstract
Multivariate time-series anomaly detection is important for server monitoring, industrial systems, and intelligent operation and maintenance. Existing point-wise and point-adjusted metrics often fail to show whether an anomalous segment is detected early enough for intervention. This paper proposes a lightweight dual-score enhancement for Anomaly Transformer. The method retains the original multiplicative anomaly score and adds window-normalized reconstruction error and association discrepancy terms, so weak deviations near anomaly onsets become more visible without changing the backbone network or using additional labels. Experiments are conducted on four public multivariate benchmarks, namely, SMD, PSM, SMAP, and MSL, under three random seeds. Compared with the original Anomaly Transformer score, the proposed early-warning union mode improves Raw Event Recall by 0.3435, 0.2408, 0.0995, and 0.0278 on SMD, PSM, SMAP, and MSL, respectively, and reduces mean detection delay by 53.66%, 49.97%, 52.69%, and 39.74%. Event precision, event F1, and false positive rate are also reported in order to make explicit the trade-off between recall and false alarms. Further range- and proximity-aware metrics additionally show that the score-level enhancement improves segment coverage and early warning behavior, while AUPRC remains dataset-dependent. The results indicate that association-discrepancy score enhancement is a practical complement to existing transformer-based anomaly detectors when early warning is more important than point-wise matching alone.
1. Introduction
Multivariate time-series anomaly detection is a key task in server monitoring, cyber–physical systems, industrial safety, and intelligent operation and maintenance [1,2,3,4]. Modern monitoring platforms collect correlated variables such as CPU utilization, network traffic, memory usage, disk input/output, and status indicators. Faults, attacks, or performance degradation often appear as continuous abnormal segments or association changes rather than isolated points.
Deep models have improved anomaly detection by learning nonlinear temporal and cross-variable patterns [5,6,7,8,9,10,11,12,13,14]. Among them, Anomaly Transformer is relevant because it uses association discrepancy between learned series associations and prior associations as an anomaly-related signal [15]. This mechanism can reflect not only large reconstruction errors but also disruptions in temporal association.
Despite these advances, evaluation remains a practical challenge. Point-wise precision, recall, and F1 require exact alignment between predictions and labels. Point adjustment, which is widely used in time-series anomaly detection, marks an anomalous segment as correctly detected once at least one point inside the segment is hit [15,16]. This protocol improves comparability with prior work, but may hide late alarms. In early warning applications, a method that detects an anomaly near the end of its segment is less useful than one that fires near the beginning.
This paper addresses the above issue from the perspective of score construction. Instead of redesigning the backbone, we propose an enhanced lightweight association-discrepancy dual-score module for Anomaly Transformer. The module keeps the original multiplicative score and adds two window-normalized terms, namely, the reconstruction error and association discrepancy. The reconstruction error reflects numerical deviation, while the association discrepancy reflects structural mismatch; combining them at the score level strengthens early responses to weak abnormal signals.
The main contributions are as follows:
- A dual-score enhancement module is proposed for Anomaly Transformer. It combines the original score, reconstruction deviation, and association discrepancy without extra supervision.
- An early-warning-oriented evaluation is used, including PA-P, PA-R, PA-F1, event-level precision, event-level recall, mean detection delay, partial hit score, AUPRC, Affiliation-F1, PATE-style F1, Range-AUC, and VUS-style metrics.
- Experiments on SMD, PSM, SMAP, and MSL show that the proposed method consistently improves event recall and reduces detection delay, while AUPRC and point-adjusted scores reveal the expected trade-off between early warning and point-wise precision.
2. Related Work
2.1. Multivariate Time Series Anomaly Detection
Anomaly detection has been extensively studied in data mining and machine learning [1,4]. Time-series anomaly detection is more difficult because observations are temporally dependent and anomalies often cover intervals rather than individual samples [2,3]. Classical one-class or density-based methods such as One-Class SVM, support vector data description, local outlier factor, and Isolation Forest provide useful baselines, but are limited in high-dimensional temporal dependency modeling [17,18,19,20].
Deep learning methods learn temporal representations directly from data. LSTM encoder–decoder models, dynamic thresholding, prediction models, stochastic models, signature matrix methods, adversarial models, mixture models, and memory-augmented autoencoders have been used for anomaly detection [5,6,7,8,9,10,11,21,22,23]. Graph-based methods further emphasize cross-variable dependency modeling [12,13,24]. A related but distinct direction is anomaly prediction, which uses pre-anomaly temporal evidence to forecast future anomalous behavior; for example, Zhao et al. used importance-based generative contrastive learning for unsupervised time-series anomaly prediction [25]. In contrast, the present work remains an unsupervised detection study; it does not predict a future horizon, but instead modifies the score used to trigger an earlier alarm within an observed anomalous interval.
2.2. Transformer Models and Evaluation Protocols
Transformer models have become important in sequence and time-series modeling since the introduction of self-attention [26]. Informer, Autoformer, TimesNet, Temporal Fusion Transformer, PatchTST, and DeepAR-related forecasting models show the effectiveness of attention and temporal representation learning [27,28,29,30,31,32,33]. For anomaly detection, TranAD applies transformer networks to multivariate sequences [14], while Anomaly Transformer introduces association discrepancy for anomaly scoring [15].
Evaluation protocols are equally important. Point-adjusted F1 is useful for segment-level hit assessment, but does not directly measure how early the first alarm occurs [15,16]. Recent studies further point out that range-aware, proximity-aware, and volume-based criteria are needed for continuous time-series anomalies [34,35,36,37]. For monitoring systems, event precision and recall, false positive rate, detection delay, partial hit score, AUPRC, Affiliation-style F1, PATE-style F1, Range-AUC, and VUS-style scores provide a more informative view of early warning performance. Therefore, this paper reports both conventional PA metrics and early warning-oriented metrics.
3. Materials and Methods
3.1. Problem Definition
Let a multivariate time series be
where T is the sequence length and C is the number of variables. In unsupervised anomaly detection, only normal training data are used to learn the model. During testing, each time point receives an anomaly score and a binary prediction is obtained by
where is the threshold.
The model uses sliding windows. For window length w, the input ending at time t is
In the SMD experiments, and , so each batch has the shape .
3.2. Base Score and Enhanced Dual Score
Anomaly Transformer reconstructs the input window and produces attention association matrices. Let be the reconstruction of . The reconstruction error is
Let and denote the learned series association and the normalized prior association at layer ℓ. The association discrepancy is computed by a symmetric KL form:
The original multiplicative score is
Here, a larger indicates a larger mismatch between the learned and prior associations. In Equation (6), is a relative decreasing weight within the window rather than a direct anomaly-evidence term: a larger discrepancy receives a smaller multiplicative weight, while the final score still depends on its interaction with reconstruction error . This is the original Anomaly Transformer scoring mechanism.
To strengthen early abnormal responses, the proposed method normalizes both and inside the current window. For a quantity , window normalization is
where and are the window mean and standard deviation, and prevents numerical instability. The enhanced score is
where controls the contribution of association discrepancy. Thus, the apparent sign difference between Equations (6) and (8) is intentional: the base score uses discrepancy as a decreasing attention-derived weight, whereas the added term treats an unusually high discrepancy as direct evidence of association disruption. This explicit decomposition is not algebraically equivalent to the original product because the standardized reconstruction and discrepancy residuals are retained as separate additive evidence. The main experiments use .
3.3. Relation to Anomaly Transformer
The proposed method uses the same trained backbone, reconstruction output, and association matrices as Anomaly Transformer; the difference lies in the construction and use of the anomaly score. The original Anomaly Transformer score multiplies reconstruction error by a softmax-transformed association-discrepancy term. While this is effective for point-wise scoring, weak onset deviations may still be suppressed when the multiplicative term is small. The proposed dual-score module explicitly re-injects the local standardized reconstruction error and association discrepancy into the final score. Therefore, the contribution is a post-training early warning enhancement at the score level rather than a new network architecture. This design is useful in deployment scenarios where retraining or changing the backbone is costly but where the alarm policy can be adjusted.
3.4. Union Early Warning Mode and Thresholding
For high-recall warning scenarios, this paper also uses a union mode:
This mode usually improves anomalous segment coverage and reduces delay, but may reduce precision.
For comparison with the original Anomaly Transformer protocol, the primary benchmark setting uses the following transductive anomaly ratio rule:
This setting uses score distributions from both the normal training sequence and the unlabeled test sequence, but never uses test labels. It is useful for controlled benchmark comparison, yet is not a fully online deployment protocol because the test score distribution is available at threshold selection time. The SMD experiments use . In union mode, the base and enhanced scores are thresholded separately.
For deployment-oriented analysis, the implementation also supports a training-only threshold:
where q is fixed before test-time inference (99.5 in the training-only threshold protocol). This inductive option avoids test score leakage, and is appropriate when a normal training reference is available. The manuscript distinguishes the transductive benchmark protocol from this training-only protocol.
3.5. Workflow
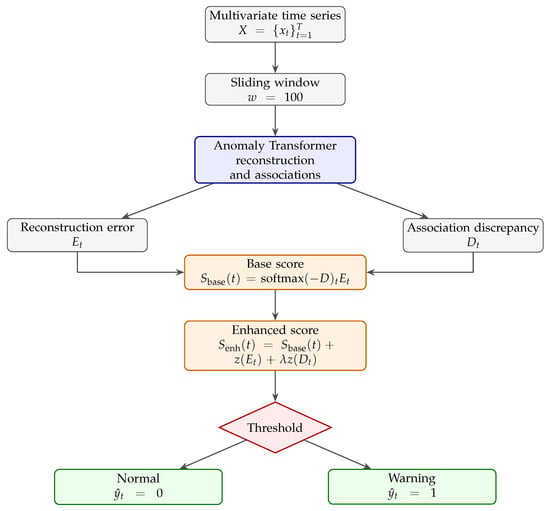
Figure 1 summarizes the method. The input series is segmented into sliding windows and passed into Anomaly Transformer. Reconstruction output and association matrices are then used to compute , , , and . The final prediction is obtained by thresholding the selected score or by using union mode.
Figure 1.
Workflow of the proposed dual-score anomaly detection method.
4. Experiments
4.1. Dataset and Settings
The experiments use four public multivariate time-series anomaly detection benchmarks: SMD, PSM, SMAP, and MSL. SMD is a server monitoring benchmark released with OmniAnomaly [8]. SMAP and MSL are spacecraft telemetry benchmarks [6]. PSM is a server machine monitoring benchmark commonly used in the Anomaly Transformer protocol [15]. Table 1 summarizes these datasets. They cover different domains and variable dimensions, which helps evaluate whether the score-level enhancement generalizes beyond a single benchmark.
Table 1.
Datasets used in the revised experiments.
The compared methods are the original Anomaly Transformer score, the proposed dual-score module, and the union early warning mode. All methods use the same Anomaly Transformer backbone. The batch size is 256, the learning rate is , the maximum number of epochs is 10, early stopping patience is 3, and the score temperature is 50.0. The input length and local normalization length are both in the main experiments. When W is varied in the sensitivity study, a model is retrained for each value so that the input representation and the score normalization context remain matched. The main results are averaged over seeds 2025, 2026, and 2027. For SMD, the sampling interval is approximately one minute, so one delay step corresponds to about one minute; for the other datasets, the delay is reported in benchmark time steps.
4.2. Evaluation Metrics
Point-level precision, recall, and F1 are
The point-level false positive rate is
which reports the fraction of normal time points that are incorrectly alarmed. PA-P, PA-R, and PA-F1 are computed after point adjustment. For event-level evaluation, let be the set of ground-truth anomalous segments and the set of predicted anomalous segments:
For a detected anomalous segment , the delay is . The mean delay and partial hit score are
AUPRC measures the area under the precision–recall curve for the anomaly scores.
We additionally report Affiliation-style F1, PATE-style F1, Range-AUC, and VUS-style metrics [34,35,36,37]. Affiliation-style precision and recall evaluate the overlap between predicted ranges and ground-truth ranges rather than isolated points. PATE-style F1 gives partial credit to predictions close to an anomalous range, so near-boundary early alarms are not treated the same as distant false alarms. Range-PR-AUC and Range-ROC-AUC integrate range-aware precision–recall and ROC behavior over thresholds. VUS-style scores further average range-AUC values over different tolerance buffer sizes. Because the main goal of this paper is early warning rather than point-wise matching, these metrics are reported only as supplementary evidence.
4.3. Main Results
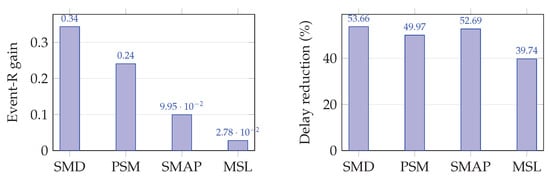
Table 2 reports the main results. The proposed method improves early warning behavior on all four datasets. Compared with the baseline, the union mode increases Raw Event Recall by 0.3435, 0.2408, 0.0995, and 0.0278 on SMD, PSM, SMAP, and MSL, respectively. The corresponding mean-delay reductions are 53.66%, 49.97%, 52.69%, and 39.74%. The dual-score module improves Event-F1 on SMD, PSM, SMAP, and MSL while maintaining a comparable or lower point-wise FPR on SMD, PSM, and SMAP. Union mode further improves event coverage and delay, but also raises FPR because it accepts alarms from either score. For example, on SMD the union FPR rises from 0.50% to 0.88%, whereas Event-R rises from 0.5372 to 0.8807 and mean delay falls from 27.55 to 12.77 steps. This makes union mode appropriate for risk-sensitive monitoring, while the single dual score is the more conservative choice. AUPRC is dataset-dependent: while it improves clearly on SMD, but it does not improve on every dataset. Therefore, the main advantage of the proposed method should be interpreted as early warning improvement rather than universal point-wise ranking improvement.
Table 2.
Main results over three random seeds. PA-F1 is computed after point adjustment; Event-P/R/F1, FPR, Delay, Partial-hit, and AUPRC are computed from raw predictions and scores. FPR is reported as a percentage. Bold values indicate the best results within each dataset.
4.4. Training-Only Threshold Analysis
Table 3 reports the deployment-oriented training-only threshold results. Compared with the benchmark transductive threshold in Table 2, the training-only protocol selects thresholds only from normal training scores, making it closer to an online deployment setting with a fixed reference distribution. The early warning pattern remains visible; on SMD, union mode reaches an Event-R of 0.8889 and reduces the mean delay to 11.6335 steps, while on PSM it improves Event-R from 0.4074 to 0.5833 and reduces the mean delay from 46.9989 to 24.8594 steps. This result also shows the expected trade-off: union mode generally raises FPR because it accepts either base-score or enhanced-score alarms, while the single dual score is more conservative. On SMAP and MSL, the training-only threshold is less favorable to the single dual score than the transductive benchmark threshold, which suggests that threshold calibration remains important for deployment.
Table 3.
Training-only threshold results. FPR is reported as a percentage.
4.5. Range- and Proximity-Aware Metrics
Table 4 reports supplementary range- and proximity-aware metrics. The enhanced scores improve Range-AUC and VUS-style scores on all datasets because the raw score distribution becomes more sensitive to anomalous regions. Union mode changes the binary prediction but uses the same enhanced score for threshold-swept metrics; therefore, its Range-AUC and VUS values are close to those of dual-score mode.
Table 4.
Range- and proximity-aware supplementary results over three random seeds. Bold values indicate the best results within each dataset.
4.6. Parameter Sensitivity
Table 5 reports the sensitivity of on SMD and PSM. On SMD, a larger value such as gives the lowest delay and the highest event recall. On PSM, however, larger values increase delay substantially, while –0.3 gives a better early warning trade-off. Therefore, is used as the main cross-dataset setting, since it is stable across both datasets rather than over-tuned to SMD.
Table 5.
Sensitivity of the discrepancy weight . Bold values indicate the best results within each dataset.
4.7. Component Ablation
Table 6 separates the contribution of the two added score terms on SMD. Adding the normalized reconstruction term provides most of the early warning gain, increasing Event-R from 0.5372 to 0.7910 and reducing delay from 27.5537 to 17.5054 steps. Adding only the normalized discrepancy term is not sufficient and reduces performance, which indicates that association discrepancy should not be used as an isolated replacement for reconstruction evidence. The complete dual-score form combining both terms provides the best Event-F1 among the ablation variants while preserving the reduced delay. This supports the design choice in Equation (8): the discrepancy term is useful as complementary association-disruption evidence when combined with reconstruction deviation rather than being used as a stand-alone detector.
Table 6.
Component ablation of the score-level enhancement on SMD. FPR is reported as a percentage. Bold values indicate the best results.
4.8. Sensitivity to Window Length
Table 7 reports the sensitivity to the input and normalization window length W on SMD. For each value, the backbone is retrained with the same window length. The dual-score method improves Event-R and Event-F1 and reduces the mean delay for all tested values of W. Increasing W from 50 to 200 improves the enhanced score’s Event-R from 0.7064 to 0.8563 and raises AUPRC from 0.0464 to 0.0530, while the delay remains at around 18–19 steps. The main experiments use because it follows the common Anomaly Transformer setting and provides a balanced context length without tuning to the best SMD sensitivity result.
Table 7.
Sensitivity to the input and normalization window length W on SMD. FPR is reported as a percentage. Bold values indicate the best results.
4.9. Cross-Dataset Early Warning Summary
Figure 2 provides a compact cross-dataset summary of the early-warning effect. Union mode improves event recall and reduces delay on all four datasets. This visual result is consistent with Table 2: the method sacrifices some point-adjusted precision in several datasets, but detects more anomalous segments and triggers alarms earlier.
Figure 2.
Cross-dataset summary of the early warning effect in union mode compared with the original Anomaly Transformer score.
4.10. Representative Temporal Case Study
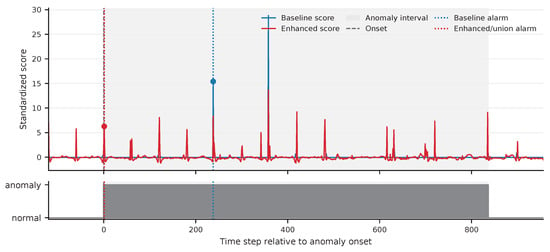
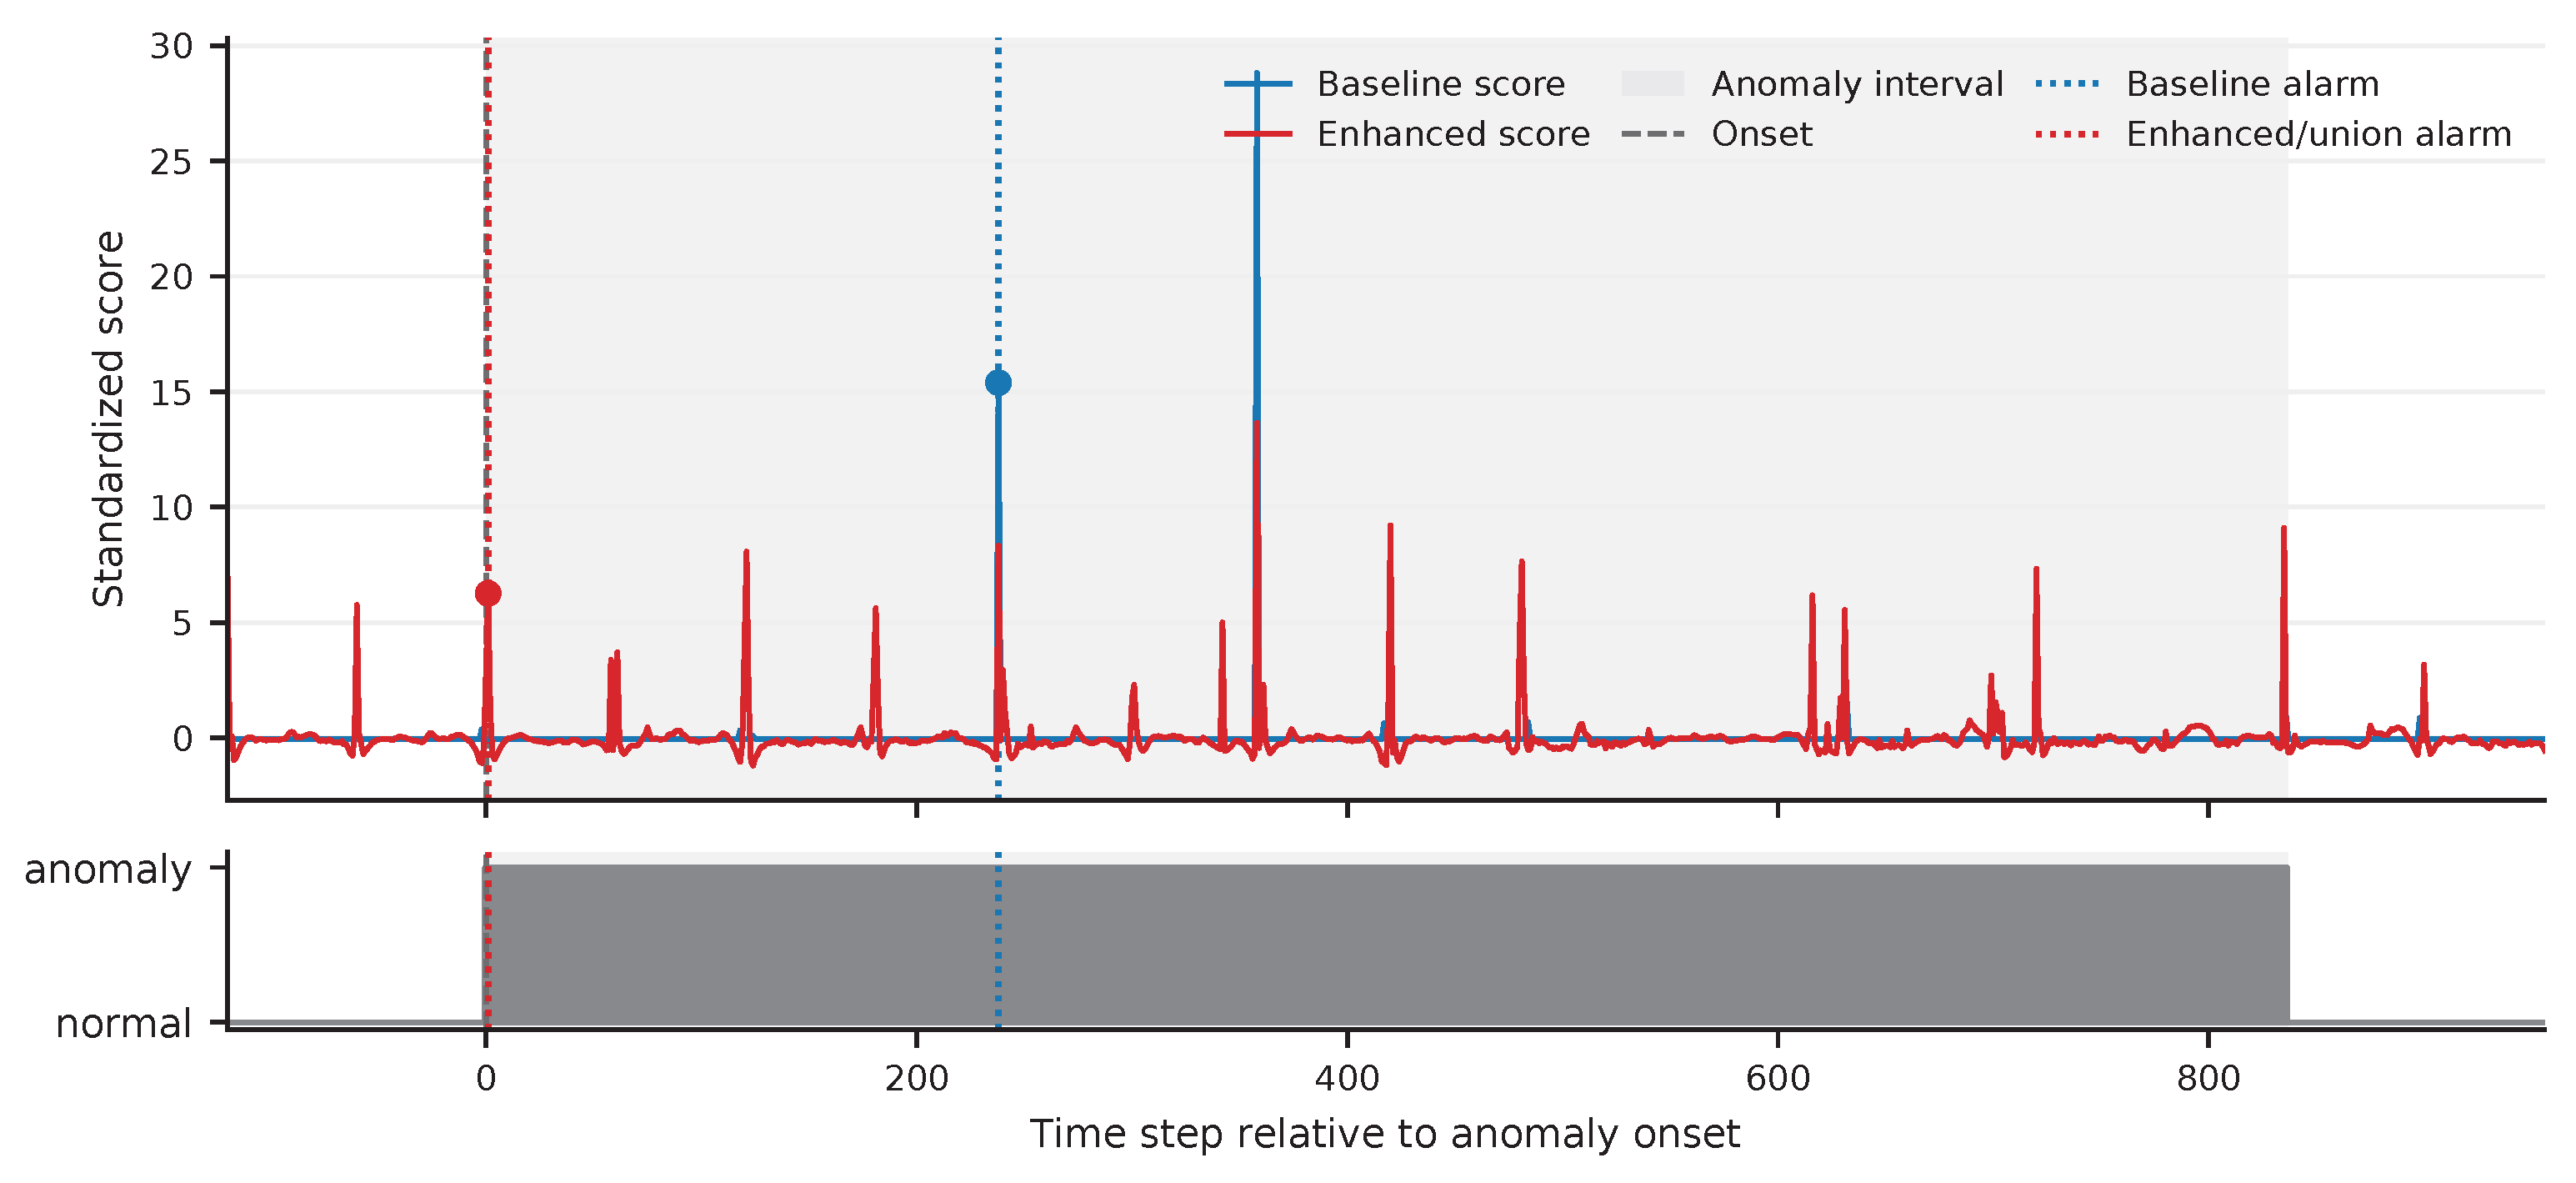
Figure 3 shows one representative SMD anomaly segment selected from the diagnostic output of the training-only threshold experiment. The ground-truth anomalous interval starts at time step 79,225 and ends at time step 80,062. In this illustrative event, the original Anomaly Transformer score first triggers an alarm at time step 79,463, corresponding to a delay of 238 sampling steps. The enhanced dual-score mode and the union mode both trigger at time step 79,226, corresponding to a delay of one sampling step. This figure is meant to illustrate the onset behavior of a single representative case, and should not be interpreted as an average delay reduction over the full dataset. The aggregate comparisons are reported in Table 2 and Table 3. This case illustrates why event-level recall alone is insufficient: while both methods can eventually hit the anomaly, the enhanced score reacts near the onset, which is more useful for early warning.
Figure 3.
Representative SMD temporal case study. The shaded region is the ground-truth anomalous interval, and the dark grey bar in the lower panel shows the binary ground-truth anomaly label. The vertical dashed line marks the anomaly onset. Dotted vertical lines mark the first alarms of the baseline and the proposed enhanced/union score. This is a single illustrative case, not a dataset-wide average; the baseline first alarm appears here at 238 sampling steps after onset, whereas the enhanced/union alarm appears after one sampling step.
5. Discussion
The results show that PA-F1 and early warning metrics can lead to different interpretations. The baseline often obtains strong PA-F1 because point adjustment rewards any hit inside an anomaly range; however, this does not guarantee that the alarm appears early. In contrast, the proposed score-level enhancement is designed to improve raw event coverage and reduce first-hit delay. This explains why union mode improves Event-R and Delay on all four datasets even when PA-F1 or AUPRC does not always improve. Event precision, Event-F1, and FPR make the corresponding operational trade-off explicit: the single dual score is generally conservative, whereas union mode gains coverage by accepting more alarms.
The method is lightweight because it uses reconstruction error and association discrepancy already produced by Anomaly Transformer, changing only the anomaly score. This makes it different from architectural methods that redesign patch encoders, memory modules, graph structures, or online adaptation mechanisms. The benefit is in its deployment simplicity: an existing trained backbone can be reused, and only the score construction and alarm policy need to be modified; more generally, the formula can be used with another detector only when that detector provides both a point-wise numerical residual and a temporally aligned relationship-disruption statistic. Importantly, this is an interface-level generalization rather than evidence that the present experiments establish empirical superiority for every backbone.
There are still a number of limitations. First, the primary benchmark threshold follows a transductive anomaly ratio protocol in order to maintain comparability with Anomaly Transformer. Although the training-only quantile alternative in Equation (11) is more appropriate for deployment, neither alternative replaces online representation adaptation under sustained distribution shift. Second, the range- and proximity-aware metrics used here are dependency-free implementations for supplementary analysis; future work should also integrate official benchmark toolkits when available. Third, union mode increases recall by design, and may introduce more false alarms; in practice, it should be selected for risk-sensitive scenarios where early warning is more valuable than maximum point-wise precision.
6. Conclusions
This paper proposed a dual-score association-discrepancy enhancement for early-warning multivariate time-series anomaly detection. By combining the original Anomaly Transformer score with normalized reconstruction error and association discrepancy, the proposed method improves early abnormal responses without additional supervision or backbone modification. Experiments on SMD, PSM, SMAP, and MSL show that the union early warning mode consistently improves Raw Event Recall and reduces mean detection delay. The improvements are especially clear on SMD and PSM. Range- and proximity-aware metrics further support the early warning benefit. AUPRC shows dataset-dependent behavior, indicating that early warning performance and point-wise ranking performance should be analyzed separately. These results support score-level enhancement as a practical complement to transformer-based anomaly detectors in early warning scenarios.
Author Contributions
Conceptualization, Z.X.; methodology, Z.X.; software, Z.X.; validation, Z.X.; formal analysis, Z.X.; investigation, Z.X.; data curation, Z.X.; writing—original draft preparation, Z.X.; writing—review and editing, W.C.; visualization, Z.X.; supervision, W.C. All authors have read and agreed to the published version of the manuscript.
Funding
This work was supported by the Basic Scientific Research Operating Expenses Program of the Department of Education of the Xinjiang Uygur Autonomous Region (Grant No. XQZX20230058).
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The SMD, PSM, SMAP, and MSL datasets analyzed in this study are publicly available from the sources cited in the manuscript and from the benchmark releases used by Anomaly Transformer. The implementation files and experiment scripts used to reproduce the reported results are available from the corresponding author upon reasonable request.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| AUPRC | Area Under the Precision–Recall Curve |
| MTS | Multivariate Time Series |
| PA | Point Adjustment |
| PATE | Proximity-Aware Time series anomaly Evaluation |
| PSM | Pooled Server Metrics |
| SMD | Server Machine Dataset |
| SMAP | Soil Moisture Active–Passive |
| VUS | Volume Under the Surface |
References
- Chandola, V.; Banerjee, A.; Kumar, V. Anomaly detection: A survey. ACM Comput. Surv. 2009, 41, 1–58. [Google Scholar] [CrossRef] [Scilit]
- Blazquez-Garcia, A.; Conde, A.; Mori, U.; Lozano, J.A. A review on outlier/anomaly detection in time series data. ACM Comput. Surv. 2021, 54, 1–33. [Google Scholar] [CrossRef] [Scilit]
- Braei, M.; Wagner, S. Anomaly detection in univariate time-series: A survey on the state-of-the-art. arXiv 2020, arXiv:2004.00433. [Google Scholar]
- Pang, G.; Shen, C.; Cao, L.; Hengel, A.V.D. Deep learning for anomaly detection: A review. ACM Comput. Surv. 2021, 54, 1–38. [Google Scholar] [CrossRef] [Scilit]
- Malhotra, P.; Vig, L.; Shroff, G.; Agarwal, P. LSTM-based encoder-decoder for multi-sensor anomaly detection. arXiv 2016, arXiv:1607.00148. [Google Scholar]
- Hundman, K.; Constantinou, V.; Laporte, C.; Colwell, I.; Soderstrom, T. Detecting spacecraft anomalies using LSTMs and nonparametric dynamic thresholding. In Proceedings of the 24th ACM SIGKDD International Conference on Knowledge Discovery and Data Mining, London, UK, 19–23 August 2018; pp. 387–395. [Google Scholar]
- Munir, M.; Siddiqui, S.A.; Dengel, A.; Ahmed, S. DeepAnT: A deep learning approach for unsupervised anomaly detection in time series. IEEE Access 2019, 7, 1991–2005. [Google Scholar] [CrossRef] [Scilit]
- Su, Y.; Zhao, Y.; Niu, C.; Liu, R.; Sun, W.; Pei, D. Robust anomaly detection for multivariate time series through stochastic recurrent neural network. In Proceedings of the 25th ACM SIGKDD International Conference on Knowledge Discovery and Data Mining, Anchorage, AK, USA, 4–8 August 2019; pp. 2828–2837. [Google Scholar]
- Zhang, C.; Song, D.; Chen, Y.; Feng, X.; Lumezanu, C.; Cheng, W.; Ni, J.; Zong, B.; Chen, H.; Chawla, N.V. A deep neural network for unsupervised anomaly detection and diagnosis in multivariate time series data. In Proceedings of the AAAI Conference on Artificial Intelligence, Honolulu, HI, USA, 27 January–1 February 2019; pp. 1409–1416. [Google Scholar]
- Audibert, J.; Michiardi, P.; Guyard, F.; Marti, S.; Zuluaga, M.A. USAD: Unsupervised anomaly detection on multivariate time series. In Proceedings of the 26th ACM SIGKDD International Conference on Knowledge Discovery and Data Mining Workshops, Virtual, 23–27 August 2020. [Google Scholar]
- Li, D.; Chen, D.; Shi, L.; Jin, B.; Goh, J.; Ng, S.K. MAD-GAN: Multivariate anomaly detection for time series data with generative adversarial networks. In Artificial Neural Networks and Machine Learning—ICANN 2019; Springer: Cham, Switzerland, 2019; pp. 703–716. [Google Scholar]
- Zhao, H.; Wang, Y.; Duan, J.; Huang, C.; Cao, D.; Tong, Y.; Xu, B.; Bai, J.; Tong, J.; Zhang, Q. Multivariate time-series anomaly detection via graph attention network. In Proceedings of the IEEE International Conference on Data Mining, Sorrento, Italy, 17–20 November 2020; pp. 841–850. [Google Scholar]
- Deng, A.; Hooi, B. Graph neural network-based anomaly detection in multivariate time series. In Proceedings of the AAAI Conference on Artificial Intelligence, Virtual, 2–9 February 2021; pp. 4027–4035. [Google Scholar]
- Tuli, S.; Casale, G.; Jennings, N.R. TranAD: Deep transformer networks for anomaly detection in multivariate time series data. Proc. VLDB Endow. 2022, 15, 1201–1214. [Google Scholar]
- Xu, J.; Wu, H.; Wang, J.; Long, M. Anomaly Transformer: Time series anomaly detection with association discrepancy. In Proceedings of the International Conference on Learning Representations, Virtual, 25–29 April 2022. [Google Scholar]
- Xu, H.; Chen, W.; Zhao, N.; Li, Z.; Bu, J.; Li, Z.; Liu, Y.; Zhao, Y.; Pei, D.; Feng, Y.; et al. Unsupervised anomaly detection via variational auto-encoder for seasonal KPIs in web applications. In Proceedings of the 2018 World Wide Web Conference, Lyon, France, 23–27 April 2018; pp. 187–196. [Google Scholar]
- Scholkopf, B.; Platt, J.C.; Shawe-Taylor, J.; Smola, A.J.; Williamson, R.C. Estimating the support of a high-dimensional distribution. Neural Comput. 2001, 13, 1443–1471. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Breunig, M.M.; Kriegel, H.P.; Ng, R.T.; Sander, J. LOF: Identifying density-based local outliers. In Proceedings of the ACM SIGMOD International Conference on Management of Data, Dallas, TX, USA, 15–18 May 2000; pp. 93–104. [Google Scholar]
- Liu, F.T.; Ting, K.M.; Zhou, Z.H. Isolation forest. In Proceedings of the IEEE International Conference on Data Mining, Pisa, Italy, 15–19 December 2008; pp. 413–422. [Google Scholar]
- Tax, D.M.J.; Duin, R.P.W. Support vector data description. Mach. Learn. 2004, 54, 45–66. [Google Scholar] [CrossRef] [Scilit]
- Zong, B.; Song, Q.; Min, M.R.; Cheng, W.; Lumezanu, C.; Cho, D.; Chen, H. Deep autoencoding Gaussian mixture model for unsupervised anomaly detection. In Proceedings of the International Conference on Learning Representations, Vancouver, BC, Canada, 30 April–3 May 2018. [Google Scholar]
- Gong, D.; Liu, L.; Le, V.; Saha, B.; Mansour, M.R.; Venkatesh, S.; Hengel, A.V.D. Memorizing normality to detect anomaly: Memory-augmented deep autoencoder for unsupervised anomaly detection. In Proceedings of the IEEE/CVF International Conference on Computer Vision, Seoul, Republic of Korea, 27 October–2 November 2019; pp. 1705–1714. [Google Scholar]
- Zhou, B.; Liu, S.; Hooi, B.; Cheng, X.; Ye, J. BeatGAN: Anomalous rhythm detection using adversarially generated time series. In Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, Macao, China, 10–16 August 2019; pp. 4433–4439. [Google Scholar]
- Chen, Z.; Chen, D.; Zhang, X.; Yuan, Z.; Cheng, X. Learning graph structures with transformer for multivariate time-series anomaly detection in IoT. IEEE Internet Things J. 2022, 9, 9179–9189. [Google Scholar] [CrossRef] [Scilit]
- Zhao, K.; Zhuang, Z.; Guo, C.; Miao, H.; Jensen, C.S.; Cheng, Y.; Yang, B. Unsupervised time series anomaly prediction with importance-based generative contrastive learning. In Proceedings of the 31st ACM SIGKDD Conference on Knowledge Discovery and Data Mining, Toronto, ON, Canada, 3–7 August 2025. [Google Scholar]
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, L.; Gomez, A.N.; Kaiser, L.; Polosukhin, I. Attention is all you need. In Advances in Neural Information Processing Systems; Curran Associates: Red Hook, NY, USA, 2017. [Google Scholar]
- Zhou, H.; Zhang, S.; Peng, J.; Zhang, S.; Li, J.; Xiong, H.; Zhang, W. Informer: Beyond efficient transformer for long sequence time-series forecasting. In Proceedings of the AAAI Conference on Artificial Intelligence, Virtual, 2–9 February 2021; pp. 11106–11115. [Google Scholar]
- Wu, H.; Xu, J.; Wang, J.; Long, M. Autoformer: Decomposition transformers with auto-correlation for long-term series forecasting. In Advances in Neural Information Processing Systems; Curran Associates: Red Hook, NY, USA, 2021. [Google Scholar]
- Wu, H.; Hu, T.; Liu, Y.; Zhou, H.; Wang, J.; Long, M. TimesNet: Temporal 2D-variation modeling for general time series analysis. In Proceedings of the International Conference on Learning Representations, Kigali, Rwanda, 1–5 May 2023. [Google Scholar]
- Lai, G.; Chang, W.C.; Yang, Y.; Liu, H. Modeling long- and short-term temporal patterns with deep neural networks. In Proceedings of the 41st International ACM SIGIR Conference on Research and Development in Information Retrieval, Ann Arbor, MI, USA, 8–12 July 2018; pp. 95–104. [Google Scholar]
- Lim, B.; Arik, S.O.; Loeff, N.; Pfister, T. Temporal fusion transformers for interpretable multi-horizon time series forecasting. Int. J. Forecast. 2021, 37, 1748–1764. [Google Scholar] [CrossRef] [Scilit]
- Nie, Y.; Nguyen, N.H.; Sinthong, P.; Kalagnanam, J. A time series is worth 64 words: Long-term forecasting with transformers. In Proceedings of the International Conference on Learning Representations, Kigali, Rwanda, 1–5 May 2023. [Google Scholar]
- Salinas, D.; Flunkert, V.; Gasthaus, J.; Januschowski, T. DeepAR: Probabilistic forecasting with autoregressive recurrent networks. Int. J. Forecast. 2020, 36, 1181–1191. [Google Scholar] [CrossRef] [Scilit]
- Tatbul, N.; Lee, T.J.; Zdonik, S.; Alam, M.; Gottschlich, J. Precision and recall for time series. In Advances in Neural Information Processing Systems; Curran Associates: Red Hook, NY, USA, 2018. [Google Scholar]
- Huet, A.; Navarro, J.M.; Rossi, D. Local evaluation of time series anomaly detection algorithms. In Proceedings of the 28th ACM SIGKDD Conference on Knowledge Discovery and Data Mining, Washington, DC, USA, 14–18 August 2022; pp. 635–645. [Google Scholar]
- Paparrizos, J.; Boniol, P.; Palpanas, T.; Tsay, R.S.; Elmore, A.; Franklin, M.J. Volume under the surface: A new accuracy evaluation measure for time-series anomaly detection. Proc. VLDB Endow. 2022, 15, 2774–2787. [Google Scholar]
- Ghorbani, R.; Reinders, M.J.T.; Tax, D.M.J. PATE: Proximity-aware time series anomaly evaluation. In Proceedings of the 30th ACM SIGKDD Conference on Knowledge Discovery and Data Mining, Barcelona, Spain, 25–29 August 2024; pp. 872–883. [Google Scholar]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.