


Abstract
Static software engineering benchmarks such as SWE-bench suffer from three fundamental limitations: task sets are fixed and become saturated as model capabilities rapidly improve; expert construction is costly and slow; and difficulty levels cannot adapt to evolving model abilities. We present SEBGen, a self-evolving benchmark generation framework that synthesizes evaluation tasks from code repositories and continuously updates its generation strategies through an evolution loop. SEBGen introduces three key innovations: an explicit five-dimension exploration value evaluator that quantitatively scores generation strategies across quality, novelty, difficulty coverage, skill diversity, and evolution potential, replacing implicit LLM judgments; a hybrid validation pipeline combining three mechanical checks (schema, compile, functional), an LLM-based semantic assessment, and a repeated-judgment gate; and a self-evolving loop with archive-based experience accumulation, sigmoid-scaled parent selection, and LLM-driven strategy mutation. On a synthetic corpus, SEBGen achieves a 96 percent stage-level validation pass rate (E1; 48/50 stage observations) and preserves generation quality through the evolution loop while showing no measurable improvement over a budget-matched non-evolution baseline. On a real repository, it generates candidate benchmark tasks from all six tqdm commits that passed the schema and LLM-based screening stages, although the compile and functional stages could not be executed because these tasks carry no test patch. A judge-level comparison against SWE-bench Lite, partially corroborated by an independent judge from a different model family (Qwen), places generated real repository tasks below expert-constructed tasks (0.48 vs. 0.83 under deepseek-chat; 0.55 vs. 0.78 under qwen-plus, mean of two passes). An extension to two further repositories (requests, flask) achieves 0/4 acceptance across executed screening stages, indicating that the system does not yet transfer reliably beyond the original repository. These results provide proof-of-concept evidence of feasibility: the framework generates candidate tasks automatically, while executable verification of real-repository tasks, reliable self-improvement, and cross-repository transfer remain open problems.
1. Introduction
As Benchmark datasets have driven progress in software engineering AI, with SWE-bench [1] establishing the standard for evaluating models on real-world GitHub issues. However, the rapid advancement of large language models (LLMs) has exposed fundamental limitations of static benchmarks, summarized in Table 1.
Table 1.
Fundamental limitations of static benchmarks.
This work addresses four research questions (RQs):
- RQ1: Can LLMs automatically generate software engineering benchmark tasks from code repositories, and under which conditions are the generated tasks verifiable?
- RQ2: Does difficulty adaptation (ZPD-based selection) improve benchmark effectiveness?
- RQ3: Does the evolution loop improve or degrade task quality over generations?
- RQ4: Can generated benchmarks differentiate agent capabilities?
Our contributions are as follows:
- Explicit Exploration Value Assessment: A five-dimension scoring model (Quality, Novelty, Difficulty Coverage, Skill Diversity, Evolution Potential) that quantifies the exploration value of generation strategies, replacing Voyager’s [2] implicit LLM judgment with interpretable, optimizable metrics.
- Hybrid Multi-Stage Validation: A validation pipeline combining three mechanical checks (schema, compile, functional), one LLM-based semantic assessment, and one repeated-judgment gate; each stage is applied where applicable—stages without applicable inputs (e.g., no test patch) are recorded as not evaluated—and acceptance requires passing all executed stages.
- Self-Evolution Loop: An archive-based experience system with sigmoid-scaled parent selection, novelty reward, and LLM-driven strategy mutation.
- Empirical Validation: Eight experiments spanning a synthetic corpus, a real repository (tqdm), and a comparison against SWE-bench Lite, covering generation quality, evolution stability, difficulty adaptation, archive-relative redundancy detection, component-level ablation, agent differentiation, and expert quality comparison.
2. Related Work
2.1. Static Software Engineering Benchmarks
SWE-bench [1] pioneered the use of real GitHub issues as evaluation tasks, with each instance containing a problem statement, test patch, and FAIL_TO_PASS/PASS_TO_PASS test specifications. While highly influential, its static nature means tasks are fixed after creation. Automated successors of SWE-bench are discussed in Section 2.4.
2.2. Self-Evolving Agents
Voyager [2] introduced automatic curriculum learning and skill library accumulation for embodied agents, using implicit LLM judgments to assess exploration value. The Darwin Gödel Machine (DGM) [3] established the archive-based evolution paradigm with parent selection and verification-driven loops. Reflexion [4] demonstrated that verbal self-reflection without weight updates can improve agent performance. ReAct [5] established the reasoning–acting paradigm underlying modern LLM agents. A recent survey of self-evolving agents [6] provides a systematic taxonomy of these lines of work, and a systematic literature review of LLMs for software engineering [7] positions benchmark evaluation as a central research concern.
2.3. Benchmarks and Evaluation for Code and Agents
This subsection groups the related work into four strands; each strand motivates one design choice of SEBGen.
Code-generation benchmarks and models. Beyond repository-level issue benchmarks, the field has produced a long line of function-level benchmarks and models: HumanEval (Codex) [8], MBPP [9], StarCoder [10], LiveCodeBench [11], RepoBench [12], and EvalPlus [13]; competitive programming was addressed by AlphaCode [14]. These efforts show that benchmark-driven evaluation is the standard instrument for measuring code capability—the practice SEBGen extends from static to self-evolving task sets.
Agent evaluation. For general-purpose agents, AgentBench [15] and WebArena [16] provide interactive- environment evaluation, while tool-augmented and self-instructed agents were pioneered by Toolformer [17] and Self-Instruct [18]. SWE-agent [19] demonstrated that a well-designed agent–computer interface substantially raises automated issue-resolution performance, which motivates our choice of exposing tasks through a uniform evaluation protocol.
Real-bug databases. Classic real-bug databases such as Defects4J [20] motivate our repository-commit-based task sourcing: mining real fix commits is a scalable way to obtain authentic task material.
Multidimensional evaluation of LLM-generated artifacts. Recent work has developed multidimensional evaluation indices for LLM-generated artifacts, e.g., trustworthiness scoring for unit test generation [21], which shares our motivation of replacing single-metric judgment with explicit multi-criteria assessment; the limitations of single-LLM judging are documented by MT-Bench [22], which motivates our hybrid mechanical-plus-LLM validation design.
2.4. Automated Benchmark Generation
Two recent industrial efforts have targeted automated benchmark generation at scale. Auto-SWE-Bench [23] (Turing, NeurIPS 2025 Exhibitor Track) continuously sources GitHub issues and pull requests to produce multilingual datasets with reproducibility guarantees. SWE-Bench++ [24] extends this line with a four-stage pipeline—programmatic PR sourcing, environment synthesis, state-differential test-oracle extraction, and a four-layer quality assurance scheme (environment determinism, oracle consistency, LLM-judge semantic alignment, and false-negative filtering)—yielding 11,133 verified instances across 3971 repositories and 11 languages.
SEBGen differs from these systems in two fundamental ways. First, SWE-Bench++ optimizes for static scale: it produces a large, one-shot corpus (with contamination-aware temporal splits for evaluation). SEBGen instead optimizes for dynamic freshness: an evolution loop continuously regenerates tasks as agent capabilities grow, with archive-based novelty tracking reducing dataset redundancy. Second, SWE-Bench++’s quality assurance is correctness-oriented (all four layers verify environment and oracle integrity), whereas SEBGen augments mechanical verification with semantic quality evaluation (LLM-as-judge clarity/solvability/novelty scoring) and an explicit five-dimension exploration value model that scores the generation strategy itself—a level of meta-evaluation absent from prior automated generators. A detailed comparison is provided in Section 5.
2.5. Comparative Positioning
Table 2 positions SEBGen relative to prior work.
Table 2.
Positioning of SEBGen relative to prior work.
3. Materials and Methods
3.1. System Architecture
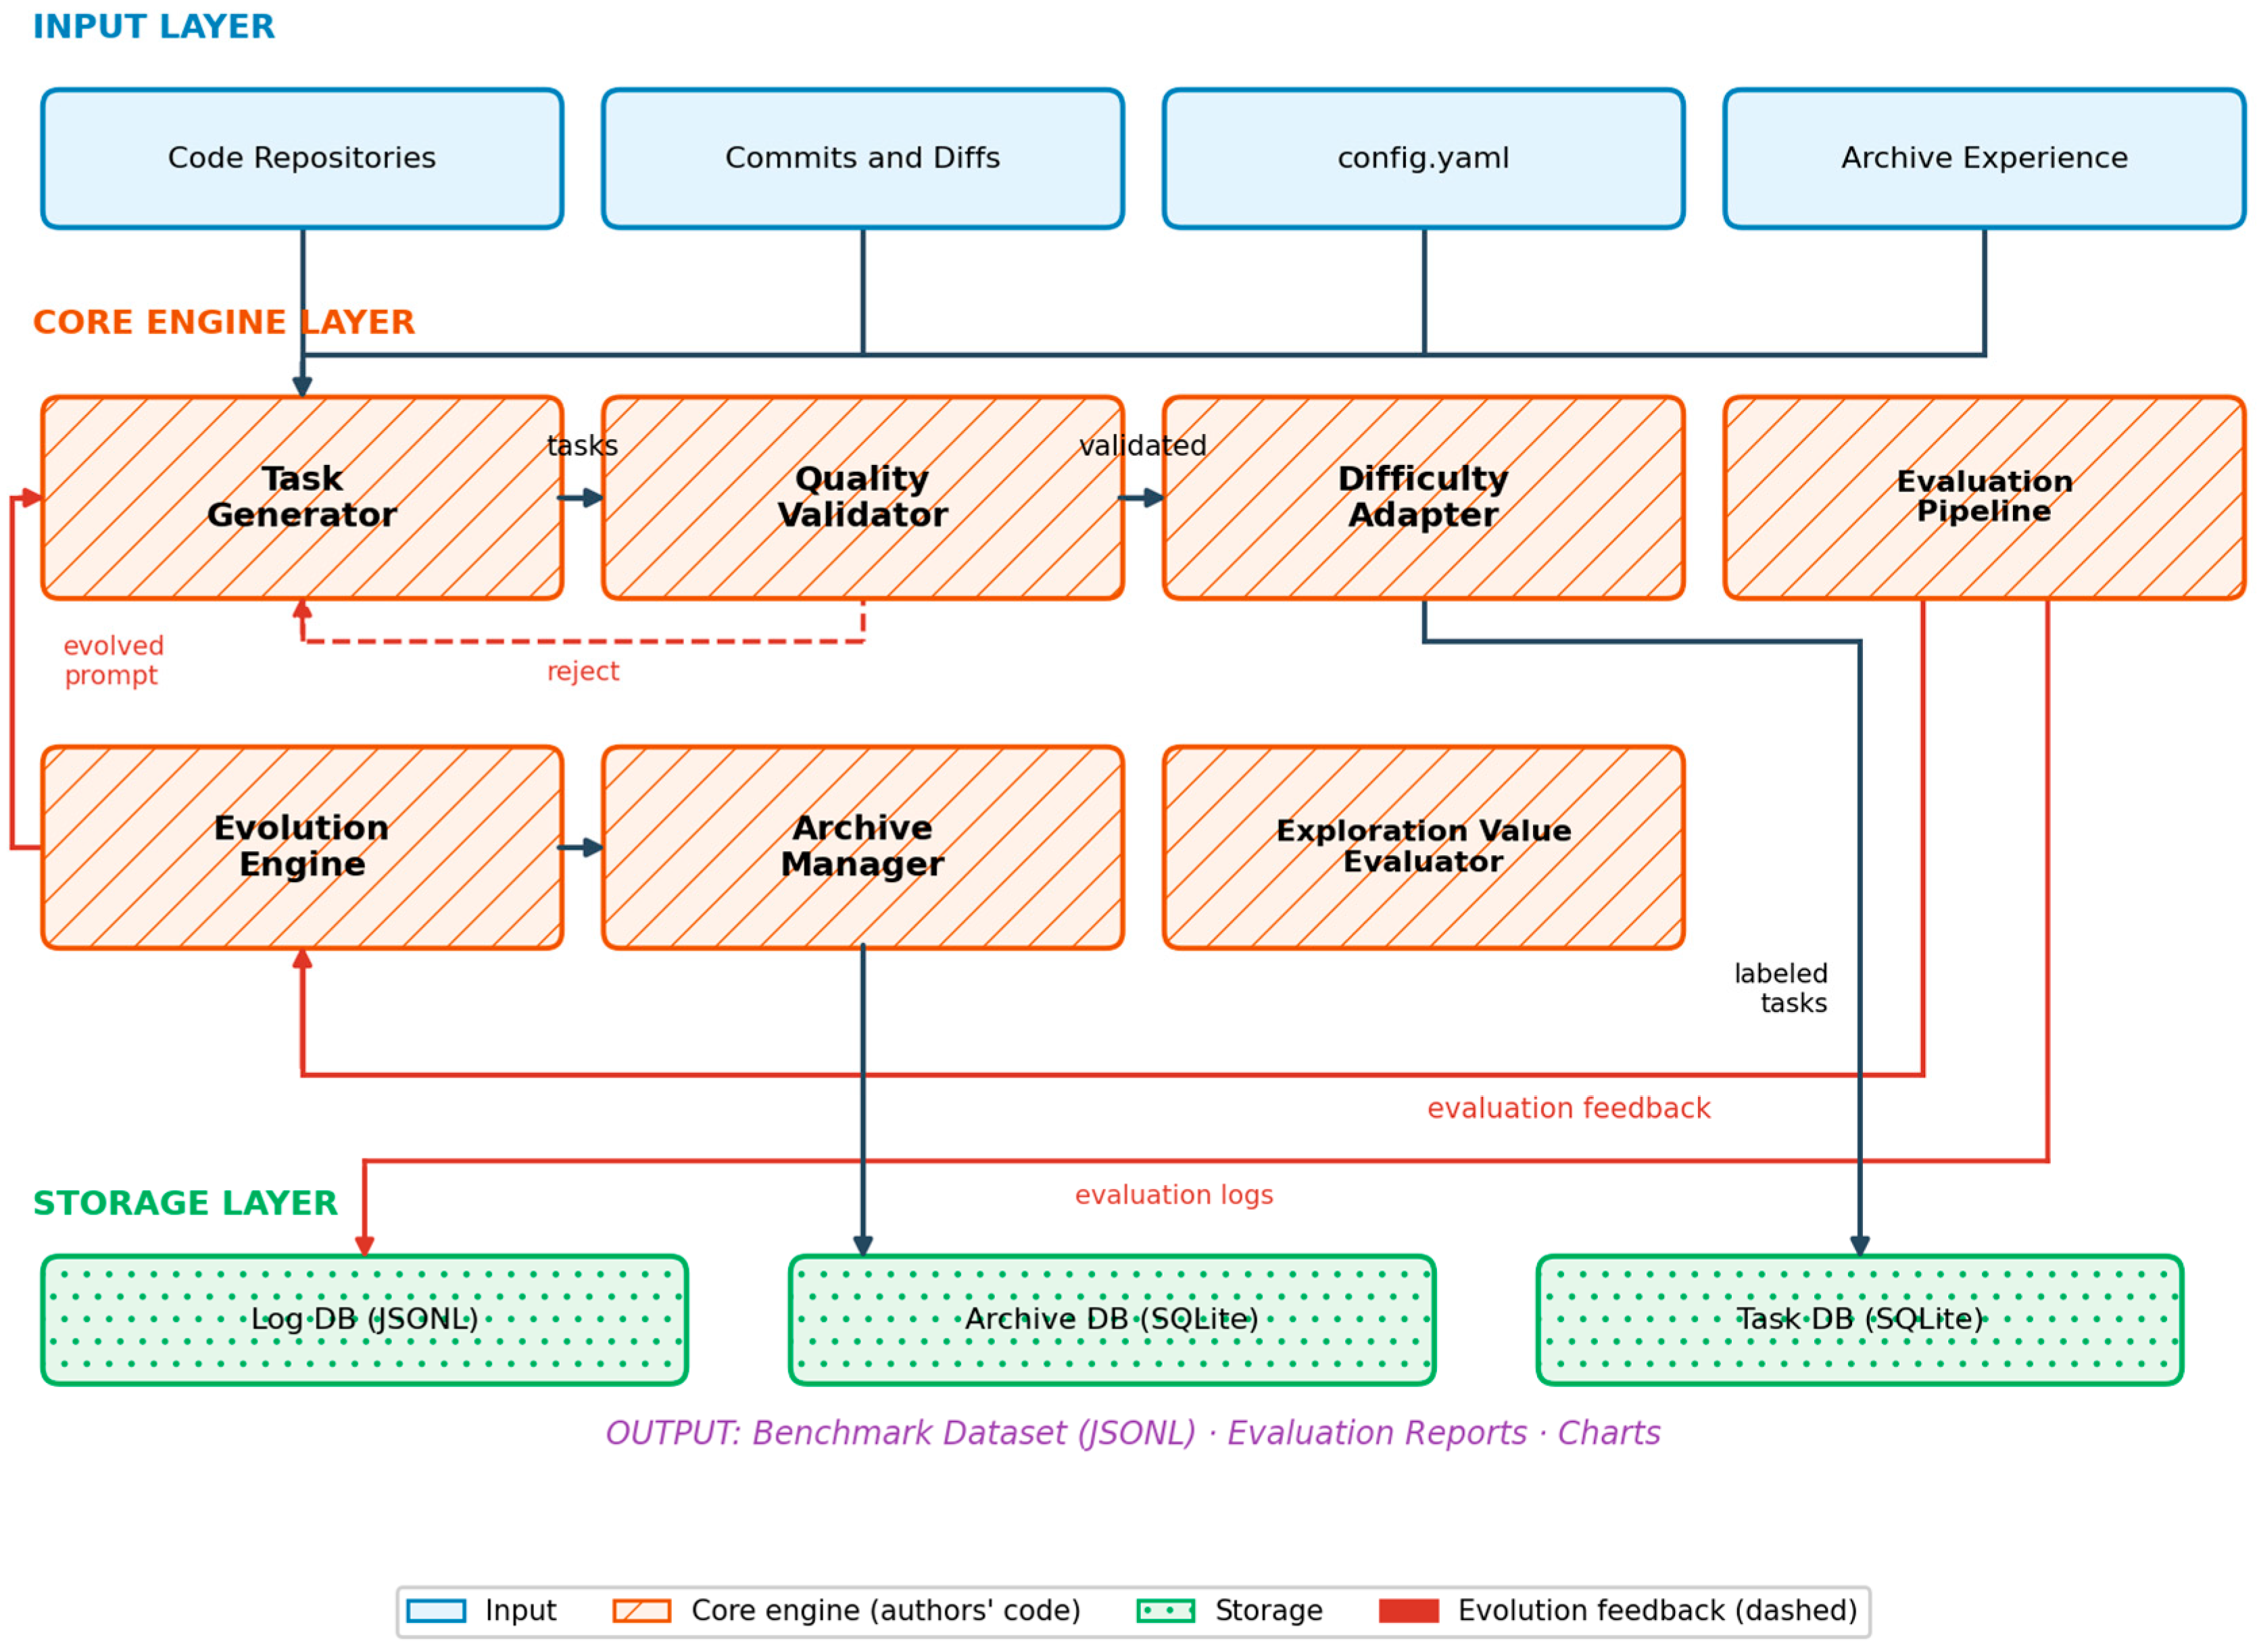
SEBGen consists of nine components: six core pipeline components (TaskGenerator, QualityValidator, DifficultyAdapter, EvaluationProtocol, EvolutionEngine, ArchiveManager) organized in the closed evolution loop of Figure 1, plus three strategy-evolution components (Exploration-Value Evaluator, StrategyMutator, ParentSelector) that operate inside the loop’s feedback path and are detailed in Section 3 and Section 4. Unless stated otherwise, “components” refers to all nine.
Figure 1.
SEBGen system architecture: four layers and the closed evolution loop of six core components. Solid arrows denote data flow; dashed red arrows denote the evolution feedback loop.
As the system follows six design principles, summarized in Table 3.
Table 3.
Six design principles and their architectural embodiment.
3.2. Software Architecture Description
Following the software description methodology of [25], we document SEBGen’s architecture in terms of its static structure (components, interfaces, and dependencies) and its dynamics (the evolution-loop message flow), and we make explicit which parts of the software were written by the authors and which are third-party dependencies. Note that the four layers of Figure 1 describe the logical system structure (input, core engine, storage, output), while the three tiers below describe the software implementation; the two views are orthogonal.
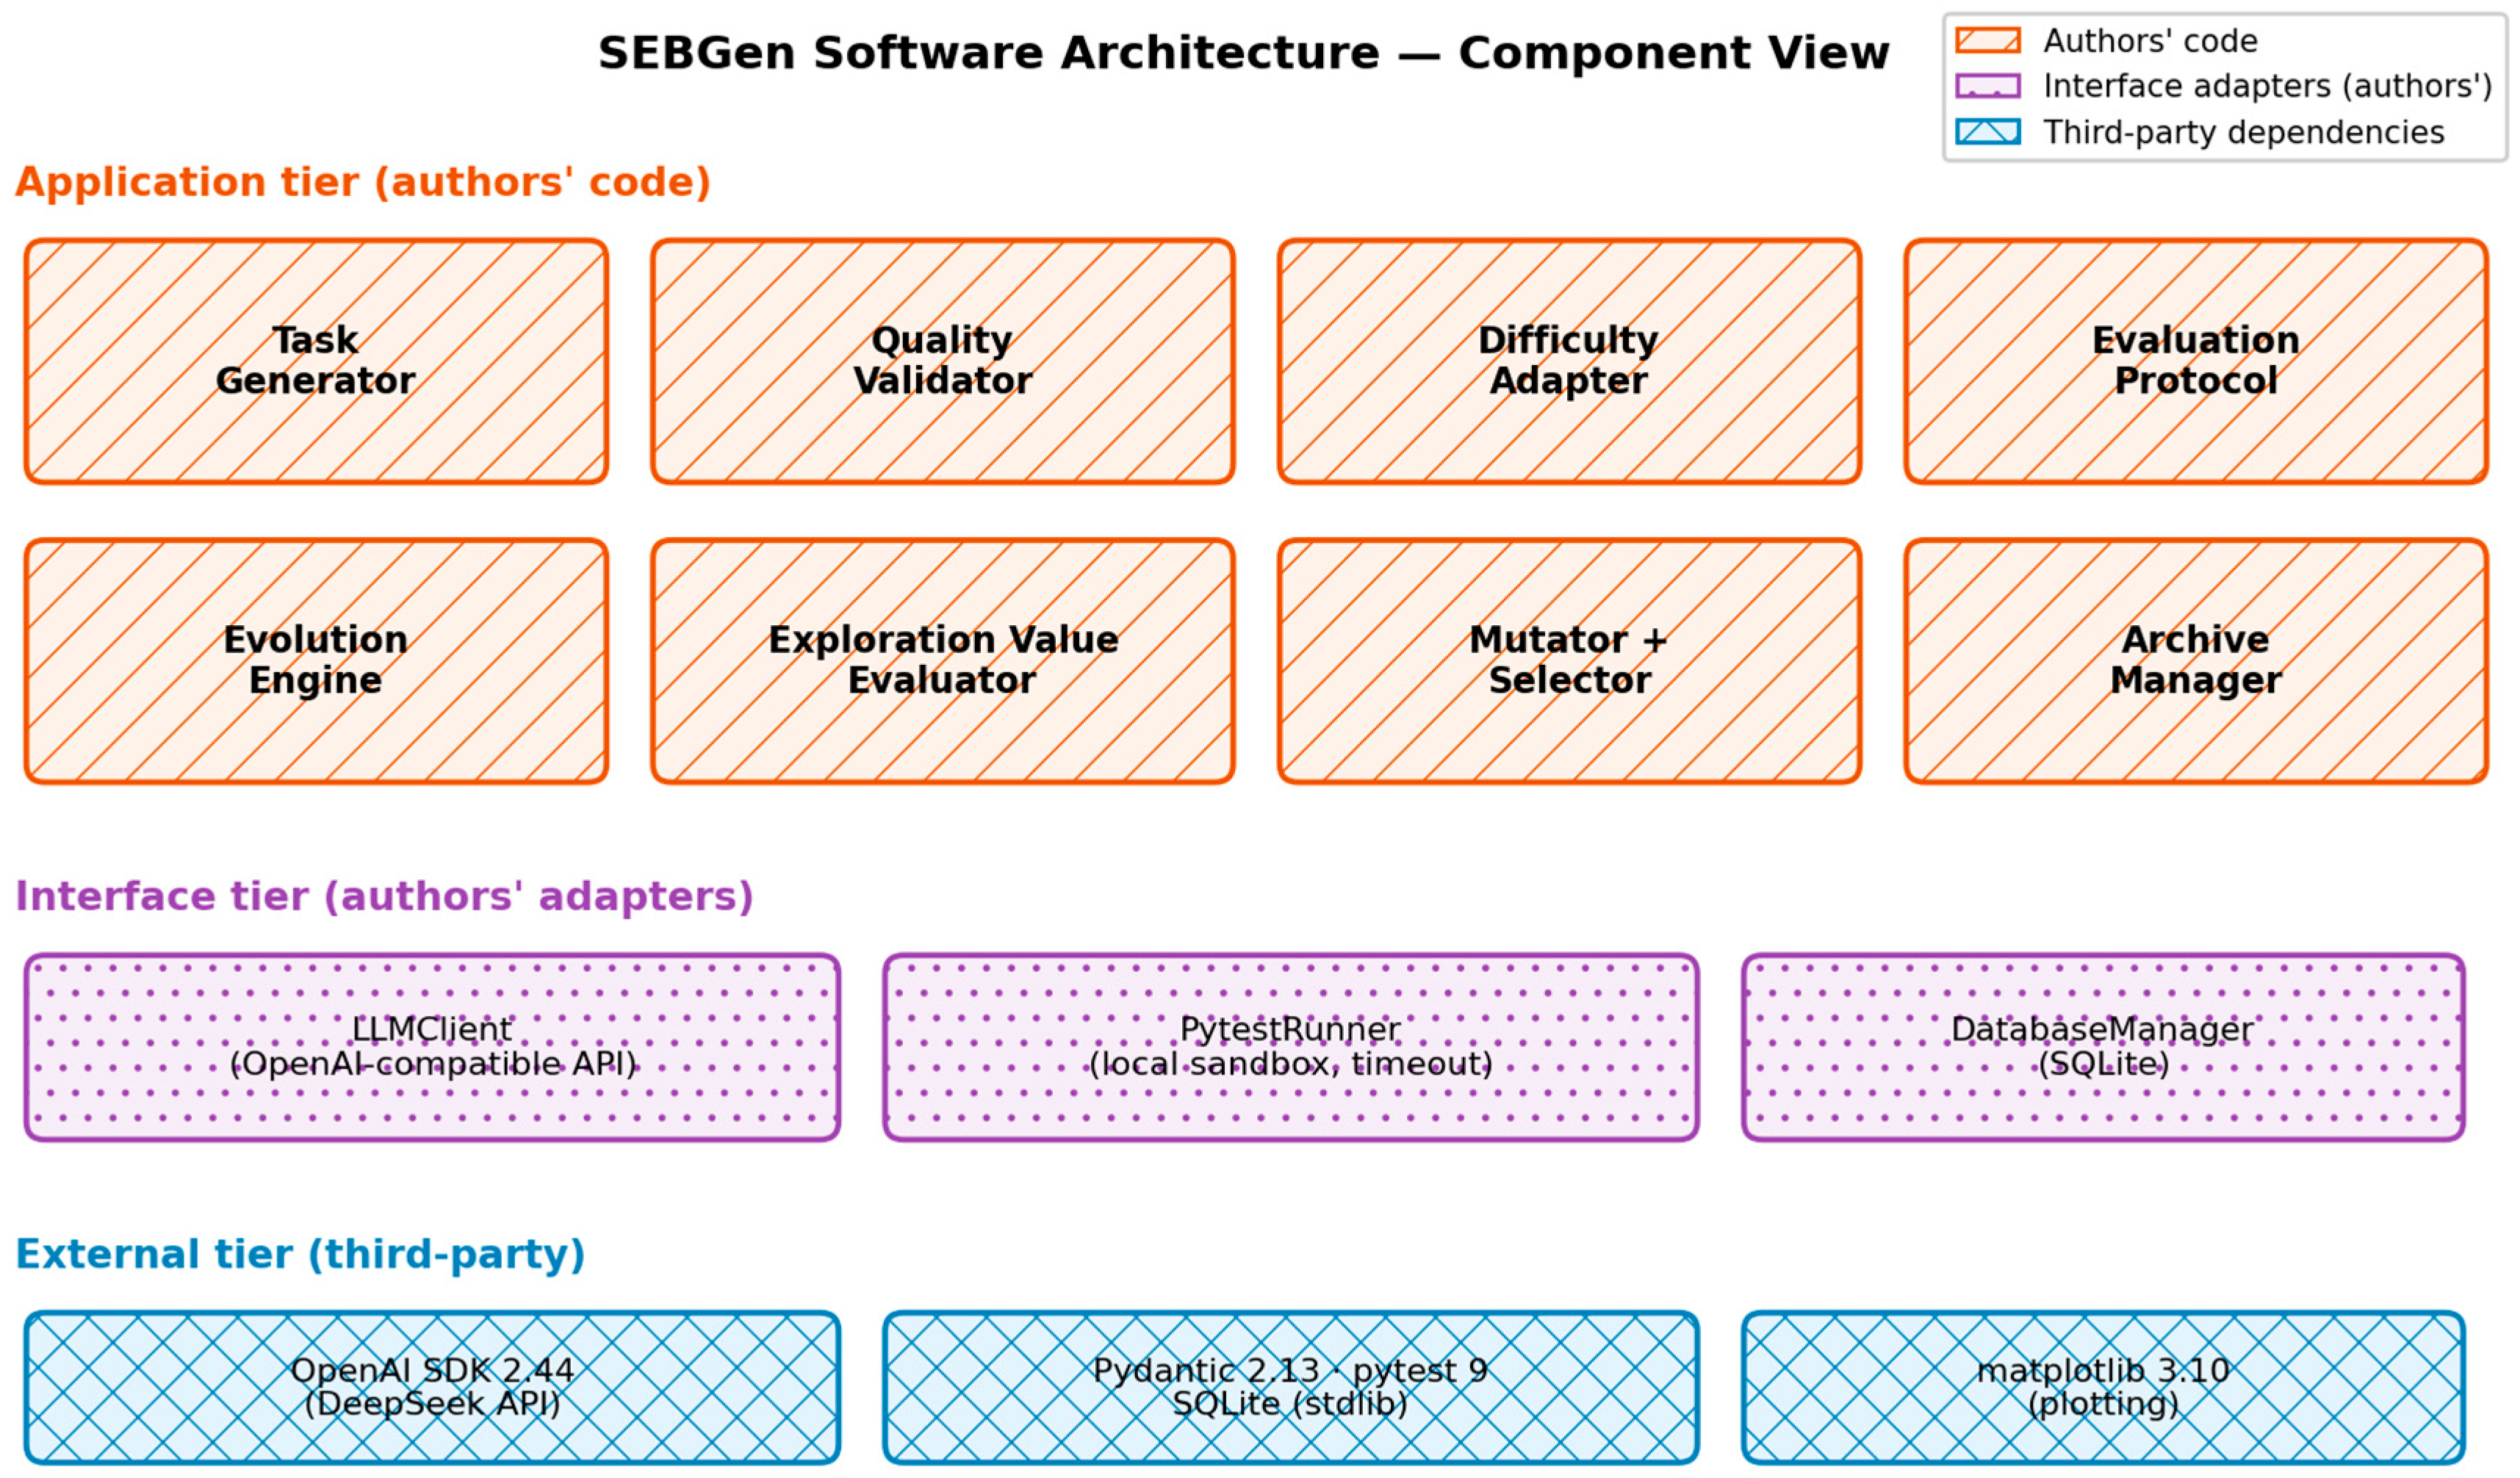
Structure. Figure 2 presents the component view. SEBGen is organized in three tiers. The application tier comprises the nine framework components written by the authors (TaskGenerator, QualityValidator, DifficultyAdapter, EvaluationProtocol, EvolutionEngine, Exploration-Value Evaluator, StrategyMutator, ParentSelector, and ArchiveManager), each implemented as a single Python 3.10.18 module with a Pydantic-typed interface. The interface tier contains three adapter modules (also authored by us) that isolate all interactions with the external environment: LLMClient (a unified chat/JSON-returning API over the OpenAI-compatible protocol), PytestRunner (local sandboxed test execution with timeout control), and Database Manager (SQLite persistence). The external tier lists third-party dependencies: the OpenAI SDK (LLM access), Pydantic v2 (schema validation), pytest (test execution), SQLite (stdlib, storage), and matplotlib (figure generation). No other runtime dependencies exist. Table 4 summarizes the authorship and origin of every component.
Figure 2.
Component view of the SEBGen software architecture. Orange boxes are code written by the authors; purple boxes are interface adapters (also authored); blue boxes are external dependencies.
Table 4.
Authored code versus external dependencies.
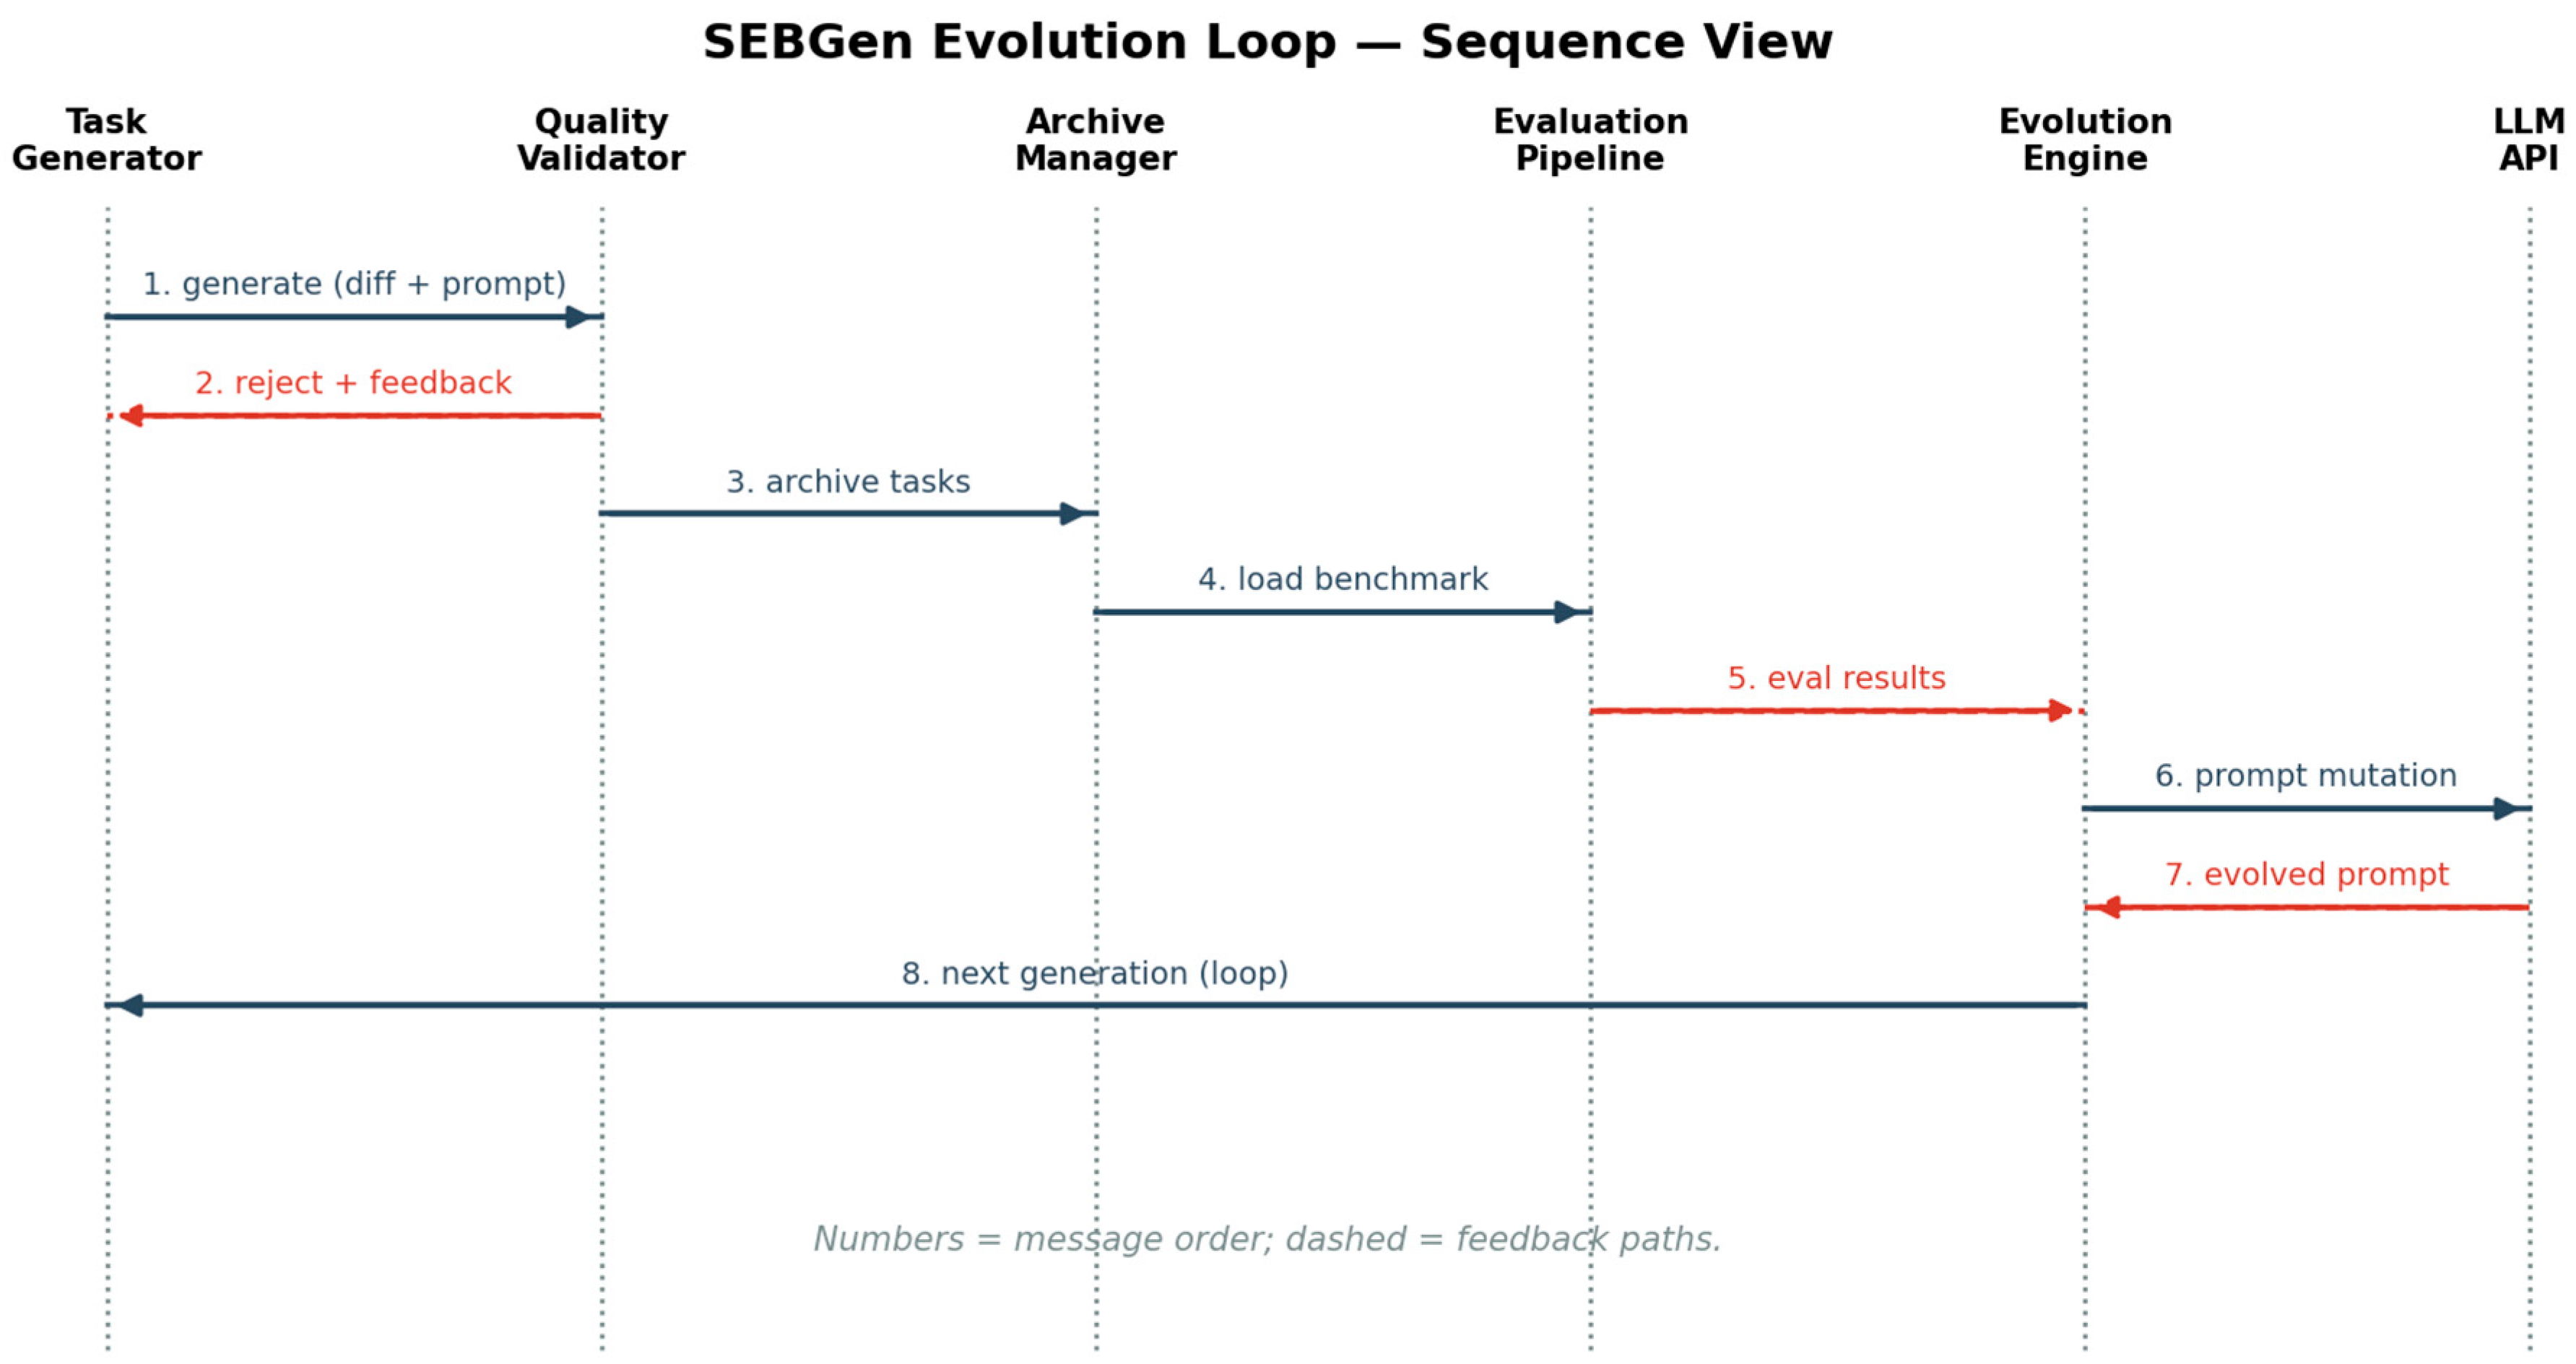
Dynamics. Figure 3 shows the message sequence of one evolution-loop iteration: (1) the TaskGenerator issues LLM calls to synthesize candidate tasks from commit diffs; (2) the QualityValidator either rejects candidates (returning failure feedback to the generator’s next batch) or forwards them; (3) accepted tasks are stored by the ArchiveManager; (4) the EvaluationProtocol loads benchmark tasks foragent evaluation; (5) evaluation results flow back to the EvolutionEngine; (6)–(7) the EvolutionEngine requests LLM-driven prompt mutation and receives the evolved prompt; (8) the evolved prompt drives the next generation round. Steps (1)–(8) repeat until a generation budget is exhausted.
Figure 3.
Sequence view of the evolution-loop dynamics. Numbers indicate message order; red arrows are feedback paths.
3.3. Task Generator
The Task Generator extracts candidate commits from code repositories and synthesizes structured benchmark tasks using LLMs with four prompt strategies: BUG_FIX, FEATURE_ADD, REFACTOR, and TEST_DRIVEN, whose templates differ only in framing (a fifth identifier, HYBRID, is defined in the configuration but has no dedicated template and was not used in the reported experiments). The generation prompt provides the commit diff (truncated to 8000 characters) and specifies the task fields to output as structured JSON. Batch generation processes up to ten diffs per batch; unparseable LLM responses are discarded without retry, and only successfully parsed candidates enter the validation pipeline.
3.4. Hybrid Multi-Stage Validation
As The validation pipeline comprises five stages—three mechanical checks (L1 schema, L2 compile, L3 functional), one LLM-based semantic assessment (L4), and one repeated-judgment gate (L5)—summarized in Table 5. Each stage is applied where applicable; stages without applicable inputs are recorded as not evaluated. Per-stage outcomes are reported for all tasks (including tasks rejected by another stage); acceptance requires passing all executed stages.
Table 5.
The hybrid validation pipeline: three mechanical checks, one LLM-based semantic assessment, and one repeated-judgment gate.
For each FAIL_TO_PASS test, the L3 functional validator verifies two phases: (1) the test fails on the original code state, and (2) the test passes after applying the reference solution. This dual-phase protocol eliminates “vacuous” tests that pass without any fix. When a task carries no test patch and no FAIL_TO_PASS tests, L3 is recorded as not evaluated: in the framework’s result schema, a stage without applicable inputs is stored explicitly as evaluated = false, passed = null, score = null, status = “not_evaluated”, so that missing functional evidence can never be counted as a pass. Non-evaluated stages are excluded from the acceptance criterion, which applies to executed stages only, and a not-evaluated L3 must not be read as executed test coverage. L2 parses the test patch that accompanies a task—the only code object the pipeline handles, since the generation prompt outputs no code. L5 repeats the semantic judgment as an independent second sample; because a task must pass both L4and L5, L5 acts as a second gate on the semantic assessment rather than a mechanism that flags disagreements separately—the stricter outcome of the two passes applies.
3.5. Difficulty Adapter (ZPD-Based)
Based on Vygotsky’s Zone of Proximal Development [26]—with curriculum-learning principles following Bengio et al. [27]—the adapter maintains a model capability profile and dynamically adjusts the ZPD range:
where margin adapts to recent success rates: 1.5× base margin when success > 80% (tasks too easy), and 0.5× when success < 30% (tasks too hard). With the default base margin of 0.15 and a simulated agent ability of 0.475 (Section 4), Equation (1) yields [0.325, 0.625], which is reported as [0.33, 0.62] after two-decimal display rounding. Curriculum sorting interleaves tasks (easy–medium–easy–medium–hard pattern) with hard tasks sparsely distributed.
ZPD = [current_ability − margin, current_ability + margin]
3.6. Explicit Exploration Value Evaluator
The five-dimension scoring model quantifies the exploration value of each generation strategy:
Exploration Value = 0.30Q + 0.20N + 0.15D + 0.15S + 0.20E
The five dimensions are defined in Table 6.
Table 6.
The five dimensions of the exploration value evaluator.
The weights reflect a deliberate prioritization: quality (0.30) dominates because benchmark validity is the primary requirement; evolution potential (0.20) outweighs novelty, difficulty coverage, and skill diversity because a strategy’s ability to keep improving over generations determines the loop’s long-term value. These weights are treated as tunable hyperparameters; their sensitivity is flagged in Section 5.
The Evolution Potential dimension implements a particularly important insight: strategies with clear, identifiable failure patterns receive high potential scores (0.80) because they can be improved through targeted prompt refinement, whereas strategies with uniformly high pass rates (>90%) receive low scores (0.20) due to limited headroom.
3.7. Evolution Engine with Parent Selection and Strategy Mutation
Parent Selection combines sigmoid-scaled performance with novelty reward:
where σ is the sigmoid function applied to z-scored performance values (amplifying differences when standard deviation > 0, degenerating to 0.5 when all strategies perform identically), and α = 0.7 weights exploitation over exploration.
combined = α·(performance) + (1 − α)·novelty
Strategy Mutation implements four genetic operators drawn from the classical genetic- algorithm literature [29]: (1) prompt mutation—LLM analyzes failure/success cases to improve the generation prompt; (2) parameter mutation—Gaussian perturbation of temperature, max_tokens, and top_p; (3) crossover—merges the higher-performing parent’s prompt with averaged parameters; and (4) random exploration—ε-greedy generation of entirely new strategies.
3.8. Archive Manager
The archive stores multi-dimensional experience with four index structures: a vector-semantic index (designed for embedding-based similarity search but not used in the reported experiments), strategy type, difficulty level, and domain. Key operations include archive-relative novelty computation (Jaccard token overlap in the reported experiments; see Appendix A.4 (Parameters)), failure querying for evolution learning, and success querying for generation reference.
4. Results
4.1. Experimental Setup
The corpus comprises 15 bug-fix scenarios across 7 domains (error handling, concurrency, memory, math, validation, security, algorithm). The generation LLM is DeepSeek (deepseek-chat). All five validation stages are active. Table 7 documents the execution environment.
Table 7.
Evaluation environment and software versions.
Reporting convention: Because sample sizes are modest (15 synthetic scenarios, 12 examined real commits, 30 sampled expert tasks), reported figures are point estimates; the replicated experiments are the exceptions: E1 was run twice (11 August 2026, eight minutes apart), and the E2b baseline comparison was repeated in five independent runs, reporting mean ± SD estimates and bootstrap 95% confidence intervals. No significance tests are performed, and we flag this as a validity limitation in Section 5.
Experiment run dates. The E1 script was executed twice on the same day (the second execution took place eight minutes after the first, while re-checking the pipeline); both runs are retained, and the duplication provides a limited form of replication on one checkpoint. All experiments ran against the provider-managed API alias deepseek-chat, whose checkpoint is updated by the provider without version pinning; absolute LLM scores are therefore tied to the checkpoint at the run date: E1 and E2 on 11 August 2026, E7 on 17 August 2026, the E8expert-taskscoring on 14 September 2026, the E7b re-run on 24 September 2026, and the E2b repeated runs plus the E8 calibration on 26 September 2026. Within-checkpoint comparisons (e.g., the E2 cross-generation trajectory) are unaffected by checkpoint updates, whereas cross-date absolute-score comparisons are not reproducible; the E8 cross-family comparison mitigates this by pairing the two judges under one checkpoint.
Experiment–corpus mapping. Table 8 lists, for every experiment, the corpus, the task counts, and the replication structure, so that every percentage reported in this paper can be recomputed against the corresponding denominator.
Table 8.
Experiment–corpus mapping: tasks and replication structure per experiment.
4.2. E1: Generation Quality Comparison (RQ1)
Table 9 reports the per-strategy results. Both strategies achieve a 96% validation pass rate with 100% generation success, confirming RQ1 on the synthetic corpus, where executable tests are run. The synthetic corpus carries hand-authored tests: each scenario in the experiment scripts defines a test patch and FAIL_TO_PASS tests, which are attached to the generated candidate before validation (see the public experiment scripts). BUG_FIX exhibits a slightly higher exploration value due to superior novelty scores. The Pass Rate counts stage-level observations (10 tasks × 5 stages = 50 per strategy; 48/50 passed). The Avg Score is the mean over all five stage scores per task. Because the three executed mechanical stages contribute their per-experiment means (1.0, 1.0, 0.85), 60% of that composite is constant, and the judge-only means (0.78 and 0.82) isolate the LLM-judge component. The E1 experiment was run twice on 11 August 2026 (eight minutes apart, same checkpoint); this table reports onerun, and the archive accumulated 40 tasks across the two runs, which form the synthetic group of the E8 calibration. Only the two primary strategies are reported here; a comparison of all five strategies is deferred to future work.
Table 9.
Generation quality comparison across strategies (E1, RQ1). Judge-only = mean of the L4 and L5 passes; Avg Score = mean of all five stage scores.
4.3. E2: Evolution Effectiveness (RQ3)
Table 10 reports the per-generation dimension values. Quality remains stable (0.91–0.92) across five generations, indicating a stability result: the evolution loop does not cause the quality degradation that commonly afflicts iterated LLM self-improvement loops. Because the Quality column mixes the deterministic mechanical stages with the LLM-judge component, we additionally re-scored the same 40archived tasks with the judge alone under the current checkpoint: the per-generation judge-only means are 0.57, 0.64, 0.58, 0.56, and 0.58 (mean 0.58), again with no monotonic trend—the stability result holds at the judge level as well. The judge-only means are lower than the E2-era judge component because of the checkpoint drift documented in E8; cross-generation comparisons remain valid because they are within-checkpoint. The overall exploration value is effectively flat (0.73–0.74), which we attribute to the loop’s behavior on a homogeneous corpus: when all strategies already perform well, there is little headroom for improvement. As a worked example for reproducibility, the generation-1 overall score is 0.30 × 0.9141 + 0.20 × 0.4636 + 0.15 × 0.7970 + 0.15 × 0.6500 + 0.20 × 0.800 = 0.7440. The evolution potential remains at 0.80 because every generation contained a small number of failures with identifiable patterns (two failed validation stages per generation out of 40), which the heuristic treats as an actionable improvement signal.
Table 10.
Evolution effectiveness across five generations (E2, RQ3). All dimension values are raw scores; the overall value is the weighted sum per Equation (2).
Non-evolution baseline. To test whether the evolution loop itself contributes anything beyond repeated generation with the same inference budget, we ran a budget-matched control: four rounds of generation with the original BUG_FIX prompt, never mutated, on the same corpus. To provide run-level uncertainty estimates, the full comparison was repeated in five independent runs (local pseudo-random seeds 101–105, one per run; LLM sampling remains stochastic at temperature 0.7/0.3, so runs differ in the realized generations). Table 11 reports the mean ± SD over the five runs.
Table 11.
Evolution loop versus a non-evolution baseline with the same inference budget, five independent runs (E2b; mean ± SD of per-run arm means).
The between-arm differences (−0.005 and +0.004) are an order of magnitude smaller than the run-level standard deviation of the difference (±0.013 and ±0.009), and the two arms’ confidence bands overlap almost completely. Bootstrap 95% confidence intervals of the per-run deltas (20,000 resamples) are [−0.015, +0.005] (homogeneous) and [−0.003, +0.011] (mixed); both include zero. On both corpora, the evolution loop therefore shows no measurable improvement over the budget-matched non-evolution baseline, while also showing no degradation—the loop preserves generation quality. The run-level SD of arm means (≈±0.01) quantifies the ordinary LLM sampling variability between independent runs. We therefore answer RQ3 conditionally: the evolution loop preserves generation quality without degradation, but we found no reliable improvement over a budget-matched non-evolution baseline on our corpora. A low-tier improvement observed in an uncontrolled configuration does not exceed ordinary LLM sampling variability once a baseline is introduced. Demonstrating genuine self-improvement requires larger corpora and more generations. The value of the evolution loop in the present system is therefore best described as strategy maintenance with automatic prompt adaptation—a mechanism whose optimization benefit remains to be demonstrated.
Operator-level ablation. To identify which genetic operator, if any, carries an optimization signal, we ran a targeted ablation with three generations per arm on the homogeneous corpus: (a) prompt mutation only (all other operators disabled), (b) parameter mutation only, and (c) no mutation. Table 12 reports the per-generation overall exploration values.
Table 12.
Operator-level ablation (E2c; three generations per arm, single run).
Prompt mutation is the only arm showing a monotonic upward trend (0.81 → 0.82) and achieves the highest mean, while parameter mutation does not outperform the no-mutation baseline. Because each arm isa single run of three generations, this is a suggestive rather than conclusive result; nevertheless, it isolates prompt mutation as the most plausible active driver of the evolution loop and parameter noise as ineffective on this corpus, directly addressing the question of which operators carry the optimization signal. A repeated-run operator ablation with confidence intervals remains future work.
4.4. E3: Difficulty Adaptation (RQ2)
With a simulated agent profile (4/5 successes at difficulties 0.40, 0.45, 0.50, and 0.55; one failure at 0.60), the mean ability was 0.475 and Equation (1) with margin 0.15 gave a ZPD range of [0.325,0.625], reported as [0.33, 0.62] after display rounding. Of 6 test tasks, 3 fell within ZPD, 2 below (too easy), and 1 above (too hard).
ZPD-based selection successfully identifies appropriately challenging tasks. However, rule-based difficulty estimation (weighted code metrics) shows limited discriminative power for short diffs, motivating future work on learned difficulty predictors. We therefore treat the RQ2 result as a preliminary demonstration of the mechanism rather than evidence of its benefit.
4.5. E4: Archive-Relative Redundancy Detection
Table 13 reports the novelty decay. Novelty decays monotonically with archive growth, demonstrating that the Jaccard-based score reliably detects archive-relative redundancy—near-duplicates of previously generated tasks—which can be flagged before inclusion to reduce dataset redundancy. This mechanism does not establish protection against pretraining- data contamination of downstream agents: Jaccard overlap measures lexical duplication within the generated dataset, not whether a task or its solution appeared in an LLM’s pretraining corpus. A stronger contamination analysis would require semantic similarity, repository chronology, post-training cutoffs, and explicit near-duplicate detection against external corpora, which we leave to future work.
Table 13.
Novelty score as a function of archive size (E4).
4.6. E5: Stage Selectivity Analysis
We analyze the selectivity of the validation stages at two levels: per-stage rejection rates on a common task pool, and the stage-level outcomes already reported in the attrition flow of Section 4.9.
Table 14 reports the per-stage outcomes of the E2 corpus. We quantify stage selectivity through per-stage rejection rates on identical inputs, rather than by comparing scores computed from different stage sets (which would confound the score composition with the quality signal). The aggregate pass rate over all five stages is 190/200 = 95% (this is a different corpus and therefore a different figure than the 96% of E1). On this corpus, the mechanical stages reject nothing (L1/L2: 0%), while the LLM-based stages reject 10% of stage observations each (L4/L5). The multi-repository attrition (Section 4.9) shows the same pattern on harder inputs: L1 passed all four requests/flask tasks (L2 and L3 were not evaluated), whereas L4 rejected 3/4 and L5 rejected 3/4. The LLM-based stages are therefore the only stages that exhibit measurable selectivity in our experiments. Quantifying stage contributions against a fixed external criterion (e.g., false-acceptance and false-rejection rates measured against human annotations, with the final criterion held constant across ablated pipelines) remains future work.
Table 14.
Per-stage outcomes of the E2 corpus over five generations (E5; 8 tasks per generation, hence 40 observations per stage in total).
4.7. E6: Benchmark Differentiation (RQ4)
To verify that SEBGen-generated benchmarks can differentiate agent capabilities, we evaluated three agents of varying sophistication on six synthetic-corpus tasks that passed all executed stages: an LLM-Strong agent (DeepSeek instructed to produce complete bug-fix solutions), a Script-Weak baseline (keyword-based heuristic descriptions without executable code), and a Random baseline.
Table 15 reports the agent outcomes. The benchmark separates the capable LLM agent from both baselines. However, because the two weak baselines are deliberately trivial, we interpret this as a sanity check that the benchmark is not accidentally solvable by chance, rather than as evidence of fine-grained discriminative power. To probe graded discrimination, we extended the panel with a constrained mid-tier agent (same LLM, restricted to one-sentence fix ideas without code): the code-based evaluation heuristic still scores it 0/6 (identical to the weak baseline), and an additional LLM-judged idea-correctness grading proved too lenient to separate the mid-tier from the trivial baseline. We therefore conclude that the current lightweight evaluation protocol (code- presence heuristics without test execution) provides only coarse, binary separation between code-producing and non-code-producing agents. Fine-grained discrimination among contemporary capable agents requires executing agent patches against the task test suites in an isolated environment (the P6 containerized evaluation), which is planned for cloud deployment and is beyond the scope of the present study. RQ4 is thus answered only at the coarse level.
Table 15.
Benchmark differentiation across agent baselines (E6, RQ4).
4.8. E7: Real Repository Experiment (tqdm)
To validate SEBGen beyond synthetic corpora, we ran the full pipeline on six real bug-fix commits extracted from the tqdm project (a widely used Python progress bar library), including fixes for AttributeError in close(), dynamic miniters smoothing, and concurrent processing time estimation.
Table 16 lists the six commits and their scores. All 6/6 real commits were successfully transformed into candidate benchmark tasks (100% generation success; all executed screening stages passed for 6/6 tasks). Each Quality value is the executed-stage mean over the schema stage (1.0), L4, and L5; the compile and functional stages were not evaluated for these tasks (their entries are excluded from the mean). The mechanical-stage entries are not universal constants but per-experiment means of the executed stages: E1’s synthetic corpus carries hand-authored tests, so its three mechanical stages were executed with means 1.0, 1.0, and 0.85, whereas E7’sreal-repositorytasks carry no test patch and only the schema stage was executed. The Judge-Only column isolates the LLM-judge component (mean 0.71). Because the archived tqdm tasks carry no test fields, the functional stage (L3) of E7 was not evaluated; the “all executed screening stages passed” statement therefore covers L1, L4, and L5 only. The average executed-stage mean of 0.81 is lower than that of the synthetic corpus (0.88–0.90), reflecting the greater complexity and nuance of real-world diffs. This provides preliminary evidence that SEBGen can transfer from synthetic to real repository inputs on a small, single-repository sample; generalization across repositories, languages, and issue types remains to be established.
Table 16.
Real-repository validation on tqdm bug-fix commits (E7). Quality = executed-stage mean (schema, L4, L5); Judge-Only = mean of the L4 and L5 passes. The compile and functional stages were not evaluated (no test patch) and are excluded from the mean.
4.9. E7b: Multi-Repository Extension and Pipeline Attrition
To probe generalization beyond a single project, we extended E7 to two additional repositories cloned from public mirrors: requests (HTTP library) and flask (web framework). We selected six recent bug-fix commits by the criterion “commit message contains the word fix and the commit modifies source (not documentation) files”. Two candidates were excluded before generation because their diffs were empty (merge-commit artifacts), leaving four generation attempts. Table 17 reports the full pipeline attrition across both E7 (tqdm) and E7b (requests + flask).
Table 17.
Pipeline attrition flow across repositories.
The attrition profile differs sharply across repositories. On tqdm, all six tasks passed all executed screening stages. On requests and flask—projects with more complex, cross-module production bugs (Windows registry proxy parsing, exception pickling, TLS connection- pool selection, IPv6server-nameparsing)—the LLM-based stages accepted only one of the four generated tasks each: L4 passed 1/4 (one score of 0.61; three rejections at 0.55, below the 0.60 threshold), and L5 passed 1/4 (one score of 0.62; three rejections at 0.45–0.55). As in E7, no test fields were attached in either experiment, so the compile and functional stages (L2 and L3) were not evaluated and are reported as n/e in Table 17; the L3 column therefore carries no behavioral information for these repositories. Because the observed judge scores cluster tightly around the 0.60 threshold, the 0/4 result is threshold-sensitive: at acceptance thresholds of 0.50 or 0.55 the acceptance rate across executed screening stages would be 3/4, while at 0.60 or 0.65 it is 0/4. We keep 0.60 because it is the value hardcoded in the framework: it was set as an implementation default when the validator was first implemented and has not been externally calibrated, because no human labels or executable test results are available for these tasks. This lack of an external criterion for the threshold is flagged in the limitations. Table 18 reports the item-level judge scores underlying these outcomes. L4 and L5 share the same judge prompt, aggregation, and threshold; their differing outcomes reflect LLM sampling variability between two independent passes (see Appendix A). Two readings of these rejections are possible. The validator may be doing exactly what it is designed to do—rejecting problem statements it judges unclear or unverifiable. Alternatively, the zero acceptance rate across executed screening stages (0/4) on the two larger repositories may reveal a genuine limitation: the current generation prompt and judge calibration, tuned on short well-scoped diffs, do not yet transfer to complex production bugs. All tasks in both E7 and E7b were generated without test attachments (the archived task records of both experiments have empty test fields); the tqdm tasks were nevertheless accepted by the screening stages because their problem statements are self-contained, whereas the cross-module production bugs of requests and flask yielded problem statements the judge considered unverifiable (the judge’s rejection notes for E7b explicitly cite the empty test fields). The generation prompt and the judge rubric will need recalibration on a multi-repository corpus before reliable transfer to complex production bugs can be expected. For RQ1, we therefore report generation success (10/10 attempts produced parseable tasks) separately from acceptance across executed screening stages (6/12 examined commits), and E7’s 6/6 acceptance should therefore not be read as repository-independent generalization.
Table 18.
Item-level L4/L5 judge scores of the four E7b tasks (two passes per stage are averaged; the framework’s single threshold of 0.60 applies to the overall score).
4.10. E8: Gold-Standard Comparison with SWE-Bench and Independent- Judge Calibration
To benchmark SEBGen against expert-constructed tasks, we loaded the SWE-bench Lite test split (300 real GitHub-issue tasks across 12 repositories, including django, sympy, scikit-learn, and matplotlib). To address the concern that generator and judge share the same model family (deepseek-chat), we performed a judge-level calibration: all 76 calibration tasks (30 expert tasks, 40 archived E1-corpustasks, and the 6 tqdm tasks) were re-scored under one identical protocol—the judge prompt of Section 3 with temperature 0.3, two independent passes per task, and the mean of the two passes as the task’s judge score—by two judges: the original deepseek-chat judge and an independent judge from a different model family, Qwen (qwen-plus, Alibaba DashScope, OpenAI-compatible endpoint). Neither judge sees any stage-averaged composite; the scores below isolate the LLM-judge component. (The E1 and E7 tables report stage-averaged composites that additionally include the executed mechanical stages, which are model-independent and therefore not relevant to the circularity concern.) The 40 archived tasks come from a nested structure—10 scenarios × 2 strategies × 2 runs of the same configuration—so they are repeated observations of 20 distinct scenario–strategy settings rather than 40 independent samples; group means below should be read with this nesting in mind.
Table 19 reports the group means under both judge families. Both judge families agree that SEBGen- generated real- repository tasks score below expert-constructed SWE-bench tasks (gap 0.35 under deepseek-chat, 0.23 under qwen-plus); the central comparative claim of E8 is therefore partially corroborated by an independent model family, and the judge-level gap is larger than the earlier stage-averaged composites suggested, because the mechanical stages no longer inflate the generated-task averages. The two families disagree, however, on the position of the synthetic corpus: deepseek-chat places it 0.25 below expert tasks, while qwen-plus places it essentially level with them (0.77 vs. 0.78). Across the 76 tasks, the judges correlate at Pearson r = 0.447 (Spearman ρ = 0.459), agree within ±0.1 on 57% of tasks, and agree on the 0.6-threshold pass/fail decision on 68% of tasks. The repeated-judgment design of L5 is supported by the pass-level agreement between the two repeated judgments: across the 152 judge–task pass pairs of the calibration (2 passes × 2 judges × 76 tasks), the mean absolute difference between the two passes is 0.023, and 97% of pairs yield the same pass/fail decision. This agreement is concentrated away from the threshold: non-boundary pairs (mean score outside [0.55, 0.65]) agree in 132/132 cases, whereas boundary pairs (mean within [0.55, 0.65]) agree in only 16/20—the same near-threshold instability that the E7b item-level scores exhibit (two of the four tasks flip their L4/L5 decisions across the threshold). Two observations qualify this result. First, the synthetic corpus does not outscore expert tasks at the judge level under either family; the higher stage-averaged composite of the synthetic corpus reflects the deterministic mechanical stages, not judge preference. Second, the absolute deepseek-chat scores have shifted since the original E7 run (the E7-era judge gave the six tqdm tasks 0.71 on average; the current checkpoint gives 0.48), which we attribute to provider-side checkpoint updates of the deepseek-chat model between the runs; this drift (0.23) is larger than the cross-judge spread (0.05–0.19) and must be kept in mind when reading any single-checkpoint absolute score. The cross-family comparison with Qwen mitigates this instability: the comparative conclusions rest on two independent judge families rather than on the absolute scores of any single checkpoint. These results remain descriptive (no significance test); they provide the calibration evidence required before the LLM-judged scores can support comparative quality claims.
Table 19.
Judge-level quality comparison across task sources under two judge families (E8 calibration; mean of two passes per task).
5. Discussion
5.1. Design Principle Validation
The six design principles proved effective: modular isolation (P1) enabled independent testing of 9 components (124 unit tests); verification-driven design (P2) maintained a 96% stage-level validation pass rate (E1 corpus); archive accumulation (P3) enabled redundancy tracking within the generated dataset; curriculum progression (P4) filtered tasks to ZPD; exploration- exploitation balance (P5) produced stable evolution without degradation; containerized isolation (P6) interfaces were designed for cloud deployment.
5.2. Comparison with SWE-Bench++
Given the close topical overlap, we provide an explicit comparison with SWE-Bench++ [24], the closest prior automated benchmark generator; Table 20 summarizes the design differences. The two systems optimize for different objectives and occupy complementary positions:
Table 20.
Design comparison between SEBGen and SWE-Bench++.
The two approaches are complementary rather than competing: SWE-Bench++ demonstrates that automated generation scales to production-grade multilingual corpora, while SEBGen demonstrates automatic prompt adaptation with approximate quality preservation across generations—a property SWE-Bench++ does not possess. The natural synthesis, which we identify as a primary direction for future work, is to embed the SEBGen evolution loop inside a SWE-Bench++-scale pipeline: their sourcing and environment synthesis would provide the massive, diverse initial population, while our exploration value evaluator and evolution engine would keep the resulting benchmark fresh as model capabilities advance. We also note that SWE-Bench++’s reported model performance (e.g., 36.20% pass@10 for claude-sonnet-4.5 ona 1782-instance subset) provides a valuable calibration point for future large-scale evaluations of SEBGen-generated tasks.
5.3. Limitations
- Scale: Real repository validation remains small (12 examined commits across three repositories); multi-project experiments at scale (100+ commits across 10+ repositories) remain future work.
- Difficulty Estimation: Rule-based difficulty scoring shows limited discriminative power for short diffs (all easy-labeled). A learned predictor is needed.
- Docker Dependence: Full functional-stage validation requires containerized isolation; the local pytest fallback provides weaker guarantees.
- Embedding-Based Novelty: Jaccard token overlap is a proxy for semantic similarity; sentence embeddings such as Sentence-BERT [30] would improve precision.
- LLM Judge Bias and Circularity: LLM-as-judge evaluation inherits model biases, and both the generator and the judge rely on the same model family (deepseek-chat). E8 mitigates the circularity concern with an independent judge from a different model family (qwen-plus), which partially corroborates the comparative ordering; however, the two judges show only moderate agreement (r = 0.447, ρ = 0.459, 68%pass-decisionagreement), and neither judge is anchored to human judgments. Human annotation of a validation subset remains needed for full calibration. The 0.60 acceptance threshold of the LLM judge is an implementation default without an external criterion (no human labels or executable test results are available for the real- repository tasks), and its sensitivity is reported explicitly in E7b.
- Small Samples Without Statistics: The empirical claims rest on small samples (15 synthetic scenarios, 12 examined real commits, 30 sampled expert tasks) with no significance tests; only the E2b baseline comparison provides run-level replication (five runs with mean ± SD), and the remaining comparisons must be read descriptively.
5.4. Threats to Validity
Internal validity: LLM generation is stochastic (generation temperature 0.7); the E2b baseline comparison reports run-level replication (five runs with mean ± SD), while the remaining figures come from single runs. External validity: Synthetic diffs may not represent real-world commit patterns; the tqdm experiment is a single-repository, six-commit probe. Construct validity: The exploration value dimensions are our operationalization of “good benchmark task”; both the dimension weights (0.30/0.20/0.15/0.15/0.20) and the Jaccard-based novelty proxy are design choices whose sensitivity has not been explored. Criterion validity: The LLM judge’s quality score is anchored neither to human judgments nor to a fixed model checkpoint (absolute deepseek-chat scores shifted between the original E7 run and the E8 calibration, following provider-side checkpoint updates); the E8 cross-family comparison with Qwen mitigates but does not eliminate this concern, and human calibration remains required before the metric can be treated as a reliable quality signal.
6. Conclusions
We presented SEBGen, a self-evolving benchmark generation framework addressing the staticity, manual dependency, and adaptivity limitations of traditional software engineering benchmarks. Three core innovations—explicit five-dimension exploration value assessment, hybrid multi-stage validation, and the archive-based self-evolution loop—enable automatic candidate-level benchmark generation with executable verification on the synthetic corpus and an automatically adapting generation strategy. Our experiments provide proof-of-concept evidence of feasibility: 100% generation success on a synthetic corpus, stable quality (0.91–0.92) across five evolution generations, archive-based redundancy tracking, measurable selectivity of the LLM-based validation stages, coarse differentiation between a capable LLM agent and trivial baselines, and a judge-level comparison partially corroborated by a second model family, in which generated real- repository tasks score below expert-constructed SWE-bench tasks under two independent judge families (deepseek-chat and qwen-plus). The multi-repository extension achieved 0/4 acceptance across executed screening stages, indicating that cross-repository transfer remains an open problem. The system is implemented as a modular Python framework (124 tests, 9 components).
Future work includes: (1) large-scale experiments on real GitHub repositories with statistical rigor; (2) learned difficulty prediction models; (3) embedding-based semantic novelty detection; (4) cloud-based Docker evaluation deployment; and (5) human calibration of the LLM-as-judge evaluation, complementing the cross-family judge calibration reported in E8.
Supplementary Materials
The following supporting information can be downloaded at: https://www.mdpi.com/article/10.3390/electronics15204663/s1, SEBGen_Supplementary_Data.zip—raw result files (judge_calibration_results.json; baseline_repeats.json; e2_judge_only.json; calibration_tasks.json; multi_repo_results.json; real_repo_tqdm.json), schema notes (README_supplementary_data.md), and the documented post-processing script (normalize_skip_layers.py).
Author Contributions
Conceptualization, methodology, software, validation, formal analysis, investigation, data curation, writing—original draft preparation, visualization, project administration: J.H.; writing—review and editing, supervision: Z.F., D.X., C.R. and Y.G. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The complete source code of SEBGen (nine framework components, 124 unit tests, and all experiment scripts) is publicly available at https://gitee.com/huangfanqie/SEBGen (accessed on 7 October 2026). The raw result files underlying the reported experiments are listed in the Supplementary Materials section.
Acknowledgments
The authors would like to thank the maintainers of tqdm for providing a publicly accessible repository used in the real-repository experiment, and the SWE-bench team for the public release of the SWE-bench Lite dataset.
Conflicts of Interest
The authors declare no conflicts of interest.
Appendix A. Reproducibility Details
This appendix documents the complete prompts and parameters of the generation, validation, and evolution pipelines. It is our own documentation of the implemented system every subsection below reproduces the exact prompt or parameter that is hardcoded in the corresponding source module of the public repository (https://gitee.com/huangfanqie/SEBGen (accessed on 7 October 2026)), so that each reported number can be traced to a specific source file and re-run by the reviewer.
Appendix A.1. Generation Prompts
The prompts below are reproduced verbatim from src/core/task_generator.py.
The BUG_FIX prompt template, reproduced in full below; the other three templates (FEATURE_ADD, REFACTOR, and TEST_DRIVEN) differ only in the framing sentence and the task description. A fifth strategy identifier, HYBRID, is defined in the configuration but has no dedicated template and was not used in the reported experiments.
“You are a benchmark task generator for software engineering agents. Given the following git diff from a bug-fix commit, generate a structured benchmark task.
Git Diff: {code_diff}
Generate a task in JSON format with the following fields: - problem_statement: A clear description of the bug to be fixed. Do NOT reveal the solution. - hints: A list of 1–3 general hints (not the exact fix). - difficulty: One of “easy”, “medium”, or “hard”. - estimated_steps: Estimated number of code changes needed (1–10).
Output ONLY valid JSON, no additional text.”
The system message is “You are a benchmark task generator. Always output valid JSON.” The commit diff is truncated to 8000 characters before insertion. Generation uses temperature 0.7 and max_tokens 4096.
Appendix A.2. Judge Prompt and Aggregation
The prompt and aggregation below are reproduced verbatim from src/core/quality_validator.py.
The semantic- assessment judge (stages L4 and L5) uses the following prompt:
“You are a benchmark task quality reviewer. Evaluate the following benchmark task for software engineering agents.
Task: {task_json}
Rate the task on a scale of 0.0 to 1.0 for each dimension: - clarity: Is the problem statement clear and unambiguous? (0–1) - correctness: Is the technical content correct and reasonable? (0–1) - solvability: Can the task be reasonably solved? (0–1) - novelty: Is the task distinct from common patterns? (0–1) - difficulty_accuracy: Is the difficulty label accurate? (0–1)
Output JSON with: - overall_score: weighted average (clarity*0.25 + correctness*0.2 + solvability*0.25 + novelty*0.15 + difficulty_accuracy*0.15) - issues: list of specific problems found”
A task passes the semantic assessment (L4) when overall_score ≥ 0.6. No per-dimension thresholds are applied. Stages L4 and L5 share this single judge prompt, aggregation, and threshold; L5 is an independent second sampling pass at temperature 0.3, so differences between L4 and L5 outcomes reflect LLM sampling variability. Each stage is applied where applicable—stages without applicable inputs are recorded as not evaluated. Per-stage outcomes are reported for all tasks (including tasks rejected by another stage); acceptance requires passing all executed stages. The judge uses temperature 0.3 and max_tokens 2048–3000.
Appendix A.3. Mutation Prompt
The prompt below is reproduced verbatim from src/core/strategy_mutator.py.
The prompt-mutation operator uses the following template, with {current_prompt}, {failures}, and {successes} filled per generation:
“You are a meta-optimizer for benchmark task generation prompts. Analyze the current prompt’s failures and successes, then produce an improved version.
Current Prompt Template {current_prompt}
Failure Cases (avoid these mistakes) {failures}
Success Cases (replicate these patterns) {successes}
Improvement Guidelines 1. Fix the specific issues in failure cases 2. Incorporate patterns from success cases 3. Keep the core task generation goal intact 4. Maintain JSON output format requirements
Output Return ONLY a JSON object with: - “improved_prompt”: the complete new prompt template (use {{code_diff}} as the diff placeholder)”
Appendix A.4. Parameters
All parameter values below are the defaults in src/config/settings.py and the experiment scripts.
Parse-failure policy. LLM responses that fail JSON parsing are discarded without a retry; batch generation processes up to ten diffs per batch, and only successfully parsed candidates enter the pipeline. Difficulty formula. Difficulty =0.25·min(code_lines/200, 1) + 0.20·min(file_count/10, 1) + 0.25·min(test_count/20, 1) + 0.30·llm_judge, clamped to [0, 1] and rounded to four decimals. Exploration value. Five dimensions with weights: quality 0.30, novelty 0.20, difficulty coverage 0.15, skill diversity 0.15, evolution potential 0.20. Evolution potential heuristic. Failures are categorized by error type; when the top-2 categories account for more than 50% of failures and at least two patterns exist, potential =0.80; otherwise potential follows the pass-rate bands (>0.90 → 0.20, >0.70 → 0.50, >0.40 → 0.65, else 0.75); strategies without results score 1.0. Evolution parameters. Mutation rate 0.4 per operator, exploration rate 0.15, exploitation weight α = 0.7 (sigmoid-scaled performance plus novelty reward), survival rate 0.3, ZPD margin 0.15. Stochasticity. No pseudo-random seed is fixed in the single-run experiments; stochasticity derives solely from LLM sampling (generation temperature 0.7). The six mixed-quality corpus inputs (two high, two medium, two low quality) are hardcoded in the repository script run_mixed_quality_evolution.py and are therefore reproducible. Statistical reporting. All reported figures are point estimates; no significance tests were performed. The E2b baseline comparison is the exception: it was repeated in five independent runs with local pseudo-random seeds 101–105 (one per run) and reports mean ± SD over the per-run arm means. E8 independent-judge calibration. The 76 calibration tasks (30 SWE-bench expert tasks sampled with random_state = 7 from the official SWE-bench Lite test-split parquet, the 40 archived E1-corpus tasks—10 scenarios × 2 strategies × 2 runs—and the 6 archived tqdm tasks) were scored by two judges under one identical protocol: the judge prompt of the Judge Prompt and Aggregation subsection, temperature 0.3, max_tokens 2048, two passes per task, and the mean of the two passes as the task score. The original judge is deepseek-chat; the independent judge is qwen-plus (Qwen, Alibaba DashScope, OpenAI-compatible endpoint). The calibration scripts rerun_baseline_repeats.py and independent_judge_calibration.py are included in the public repository, and the per-task scores of both judges are saved in data/experiments/phase4/judge_calibration_results.json. Neither judge was shown any stage-averaged composite or source label beyond the task JSON. Data usage and splits. No train/test split is involved (this is an evaluation study, not model training): the 15-scenario synthetic corpus and the six mixed-quality inputs are used in full; all six tqdm commits and the four non-excluded requests/flask candidates are used in full; the 30 SWE-bench tasks are drawn from the official SWE-bench Lite test split. Single-run configurations were run once; E1 was run twice (11 August 2026); and the E2b baseline comparison was run five times (seeds 101–105). Dependencies. The complete dependency list with version constraints is in pyproject.toml; key runtime versions are listed in Table 7, which serves as the key- resources table. The repository README.md documents installation and the entry points of all experiment scripts. Archive and novelty. The archive is a SQLite plus JSONL store; archive-relative novelty compares a candidate’s concatenated text fields against archived tasks with word-token Jaccard similarity (lowercased, whitespace tokenization, set intersection over union). The vector-semantic index is a designed extension and was not used in any reported experiment; all reported novelty figures use Jaccard token overlap only.
Appendix A.5. Reproducibility Checklist
- Code availability: public repository with the complete code and README at https://gitee.com/huangfanqie/SEBGen (accessed on 7 October 2026).
- Environment: Python 3.10.18 (Conda environment agent-benchmark); key package versions in Table 7; complete dependency constraints in pyproject.toml; CPU-only experiments, no GPU/CUDA used.
- Compute resources: Intel Core i7 (4 physical cores), 8 GB RAM, macOS 12.7.6; typical runtime ≈ 7 s per task (generation plus five-stage validation, three LLM calls).
- Statistical reporting: reported figures are point estimates without significance tests; the E2b baseline comparison additionally reports mean ± SD over five independent runs (seeds 101–105) with bootstrap 95% confidence intervals (20,000 resamples) on the between-arm differences; the E8 calibration reports per-task scores of two judge families.
- Data usage and splits: evaluation study without train/test splits; the 15-scenario synthetic corpus, the six mixed-quality inputs, the six tqdm commits, and the four non-excluded requests/flask candidates are used in full; the 30 SWE-bench tasks come from the official test split; single-run configurations were run once, E1 was run twice, and the E2b baseline comparison was run five times.
- Key resources: Table 7 serves as the key- resources table (hardware, software, LLM API, parameters, and runtime); README.md documents installation and experiment entry points.
Appendix A.6. Execution-SecurityControls
The controls below are implemented in src/core/evaluation_protocol.py and src/utils/pytest_runner.py.
The local pytest runner executes generated tests in a fresh temporary directory per task, with a 60 s timeout and stop-on-first-failure. Process isolation (containers) and network restriction are not provided in the reported experiments; containerized deployment is planned (design principle P6).
References
- Jimenez, C.E.; Yang, J.; Wettig, A.; Yao, S.; Pei, K.; Press, O.; Narasimhan, K. SWE-bench: Can Language Models Resolve Real-World GitHub Issues? In Proceedings of the 12th International Conference on Learning Representations (ICLR), Vienna, Austria, 7–11 May 2024. [Google Scholar]
- Wang, G.; Xie, Y.; Jiang, Y.; Mandlekar, A.; Xiao, C.; Zhu, Y.; Fan, L.; Anandkumar, A. Voyager: An Open-Ended Embodied Agent with Large Language Models. arXiv 2024, arXiv:2305.16291. [Google Scholar]
- Zhang, J.; Hu, S.; Lu, C.; Lange, R.; Clune, J. Darwin Gödel Machine: Open-Ended Evolution of Self-Improving Agents. arXiv 2026, arXiv:2505.22954. [Google Scholar]
- Shinn, N.; Cassano, F.; Berman, E.; Gopinath, A.; Narasimhan, K.; Yao, S. Reflexion: Language Agents with Verbal Reinforcement Learning. In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS 2023), New Orleans, LA, USA, 10–16 December 2023. [Google Scholar]
- Yao, S.; Zhao, J.; Yu, D.; Du, N.; Shafran, I.; Narasimhan, K.; Cao, Y. ReAct: Synergizing Reasoning and Acting in Language Models. In Proceedings of the 11th International Conference on Learning Representations (ICLR), Kigali, Rwanda, 1–5 May 2023. [Google Scholar]
- Gao, H.A.; Geng, J.; Hua, W.; Hu, M.; Juan, X.; Liu, H.; Liu, S.; Qiu, J.; Qi, X.; Wu, Y.; et al. A survey of self-evolving agents: What, when, how, and where to evolve on the path to artificial superintelligence. arXiv 2025, arXiv:2507.21046. [Google Scholar]
- Hou, X.; Zhao, Y.; Liu, Y.; Yang, Z.; Wang, K.; Li, L.; Luo, X.; Lo, D.; Grundy, J.; Wang, H. Large Language Models for Software Engineering: A Systematic Literature Review. ACM Trans. Softw. Eng. Methodol. 2024, 33, 220. [Google Scholar] [CrossRef] [Scilit]
- Chen, M.; Tworek, J.; Jun, H.; Yuan, Q.; Pinto, H.P.d.O.; Kaplan, J.; Edwards, H.; Burda, Y.; Joseph, N.; Brockman, G.; et al. Evaluating Large Language Models Trained on Code. arXiv 2021, arXiv:2107.03374. [Google Scholar]
- Austin, J.; Odena, A.; Nye, M.; Bosma, M.; Michalewski, H.; Dohan, D.; Jiang, E.; Cai, C.; Terry, M.; Le, Q.; et al. Program Synthesis with Large Language Models. arXiv 2021, arXiv:2108.07732. [Google Scholar]
- Li, R.; Ben Allal, L.; Zi, Y.; Muennighoff, N.; Kocetkov, D.; Mou, C.; Marone, M.; Akiki, C.; Li, J.; Chim, J.; et al. StarCoder: May the Source Be with You! arXiv 2023, arXiv:2305.06161. [Google Scholar]
- Jain, N.; Han, K.; Gu, A.; Li, W.-D.; Yan, F.; Zhang, T.; Wang, S.; Solar-Lezama, A.; Sen, K.; Stoica, I. LiveCodeBench: Holistic and Contamination-Free Evaluation of Large Language Models for Code. In Proceedings of the 13th International Conference on Learning Representations (ICLR), Singapore, 24–28 April 2025; pp. 25479–25519. [Google Scholar]
- Liu, T.; Xu, C.; McAuley, J. RepoBench: Benchmarking Repository-Level Code Auto-Completion Systems. In Proceedings of the 12th International Conference on Learning Representations (ICLR), Vienna, Austria, 7–11 May 2024. [Google Scholar]
- Liu, J.; Xia, C.S.; Wang, Y.; Zhang, L. Is Your Code Generated by ChatGPT Really Correct? Rigorous Evaluation of Large Language Models for Code Generation. In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS), New Orleans, LA, USA, 10–16 December 2023. [Google Scholar]
- Li, Y.; Choi, D.; Chung, J.; Kushman, N.; Schrittwieser, J.; Leblond, R.; Eccles, T.; Keeling, J.; Gimeno, F.; Lago, A.D.; et al. Competition-Level Code Generation with AlphaCode. Science 2022, 378, 1092–1097. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Liu, X.; Yu, H.; Zhang, H.; Xu, Y.; Lei, X.; Lai, H.; Gu, Y.; Ding, H.; Men, K.; Yang, K.; et al. AgentBench: Evaluating LLMs as Agents. In Proceedings of the 12th International Conference on LearningRepresentations (ICLR), Vienna, Austria, 7–11 May 2024. [Google Scholar]
- Zhou, S.; Xu, F.F.; Zhu, H.; Zhou, X.; Lo, R.; Sridhar, A.; Cheng, X.; Ou, T.; Bisk, Y.; Fried, D.; et al. WebArena: A Realistic Web Environment for Building Autonomous Agents. In Proceedings of the 12th International Conference on Learning Representations (ICLR), Vienna, Austria, 7–11 May 2024. [Google Scholar]
- Schick, T.; Dwivedi-Yu, J.; Dessi, R.; Raileanu, R.; Lomeli, M.; Hambro, E.; Zettlemoyer, L.; Cancedda, N.; Scialom, T. Toolformer: Language Models Can Teach Themselves to Use Tools. In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS), New Orleans, LA, USA, 10–16 December 2023. [Google Scholar]
- Wang, Y.; Kordi, Y.; Mishra, S.; Liu, A.; Smith, N.A.; Khashabi, D.; Hajishirzi, H. Self-Instruct: Aligning Language Models with Self-Generated Instructions. In Proceedings of the 61st Annual Meetingof the Association for Computational Linguistics (ACL), Toronto, ON, Canada, 9–14 July 2023; pp. 13484–13508. [Google Scholar]
- Yang, J.; Jimenez, C.E.; Wettig, A.; Lieret, K.; Yao, S.; Narasimhan, K.; Press, O. SWE-agent: Agent-Computer Interfaces Enable Automated Software Engineering. In Proceedings of the Advances in NeuralInformation Processing Systems (NeurIPS), Vancouver, BC, Canada, 10–16 December 2024. [Google Scholar]
- Just, R.; Jalali, D.; Ernst, M.D. Defects4J: A Database of Existing Real Bugs to Enable Controlled Testing Studies for Java Programs. In Proceedings of the 2014 International Symposium on Software Testing and Analysis (ISSTA), San Jose, CA, USA, 21–25 July 2014; pp. 437–440. [Google Scholar]
- Slotkienė, A.; Makaris, L. A Formal Trustworthiness Construct for Large Language Model-Based Test Generation: A Multidimensional Index Empirically Evaluated Through a Multi-Agent Study. Electronics 2026, 15, 3694. [Google Scholar] [CrossRef] [Scilit]
- Zheng, L.; Chiang, W.-L.; Sheng, Y.; Zhuang, S.; Wu, Z.; Zhuang, Y.; Lin, Z.; Li, Z.; Li, D.; Xing, E.; et al. Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena. In Proceedings of the Advances inNeural Information Processing Systems (NeurIPS Datasets and Benchmarks Track), New Orleans, LA, USA, 10–16 December 2023. [Google Scholar]
- Wang, L.; Ramalho, L.; Celestino, A.; Pham, P.A.; Sinha, U.K.; Portillo, A.; Portillo, A.; Osunwa, O.; Maduekwe, G. Auto-SWE-Bench: Scalable, Real-World Benchmarks for LLM Coding Evaluation. Presented at the NeurIPS 2025 Exhibitor Spot Talks, San Diego, CA, USA, 2 December 2025; Available online: https://neurips.cc/virtual/2025/loc/san-diego/talk/127742 (accessed on 27 September 2026).
- Wang, L.; Ramalho, L.; Celestino, A.; Pham, P.; Liu, Y.; Sinha, U.K.; Narváez Portillo, A.F.; Osunwa, O.; Maduekwe, G. SWE-Bench++: A Framework for the Scalable Generation of Software Engineering Benchmarks from Open-Source Repositories. arXiv 2025, arXiv:2512.17419. [Google Scholar] [CrossRef] [Scilit]
- Górski, T. Software architecture description in original software publications. Softw. Impacts 2026, 27, 100802. [Google Scholar] [CrossRef] [Scilit]
- Vygotsky, L.S. Mind in Society: The Development of Higher Psychological Processes; Harvard University Press: Cambridge, MA, USA, 1978. [Google Scholar]
- Bengio, Y.; Louradour, J.; Collobert, R.; Weston, J. Curriculum Learning. In Proceedings of the 26th Annual International Conference on Machine Learning (ICML), Montreal, QC, Canada, 14–18 June 2009; pp. 41–48. [Google Scholar]
- Lin, J. Divergence Measures Based on the Shannon Entropy. IEEE Trans. Inf. Theory 1991, 37, 145–151. [Google Scholar] [CrossRef] [Scilit]
- Holland, J.H. Adaptation in Natural and Artificial Systems: An Introductory Analysis with Applications to Biology, Control, and Artificial Intelligence; MIT Press: Cambridge, MA, USA, 1992. [Google Scholar]
- Reimers, N.; Gurevych, I. Sentence-BERT: Sentence Embeddings Using Siamese BERT-Networks. In Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing (EMNLP-IJCNLP), Hong Kong, China, 3–7 November 2019; pp. 3982–3992. [Google Scholar]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.