1. Introduction
Few online phenomena have been studied as intensively as state-backed influence operations (IOs). Since the public release of the first platform-attributed archives, a research and policy ecosystem has grown around them, and with it a set of widely repeated claims about how these operations achieve influence. Many of these claims have hardened into “stylized facts”: statements that circulate across investigative journalism, government and think-tank reporting, and the peer-reviewed literature with the confidence of settled knowledge.
This paper examines five of them: (1) that an influence operation is a
monolithic troll army, acting in concert; (2) that it
wins on emotion, that moral-emotional and outrage-laden language is what drives the spread of its content; (3) that it
manufactures its own virality through sockpuppet self-amplification; (4) that it is a
sophisticated, optimizing adversary that learns from reception and adapts what it says to what works; (5) that it has become
indistinguishable from real users’ content, or, in the mirror-image folk belief, that it is still detectable by the crude linguistic tics of the 2016-era troll.
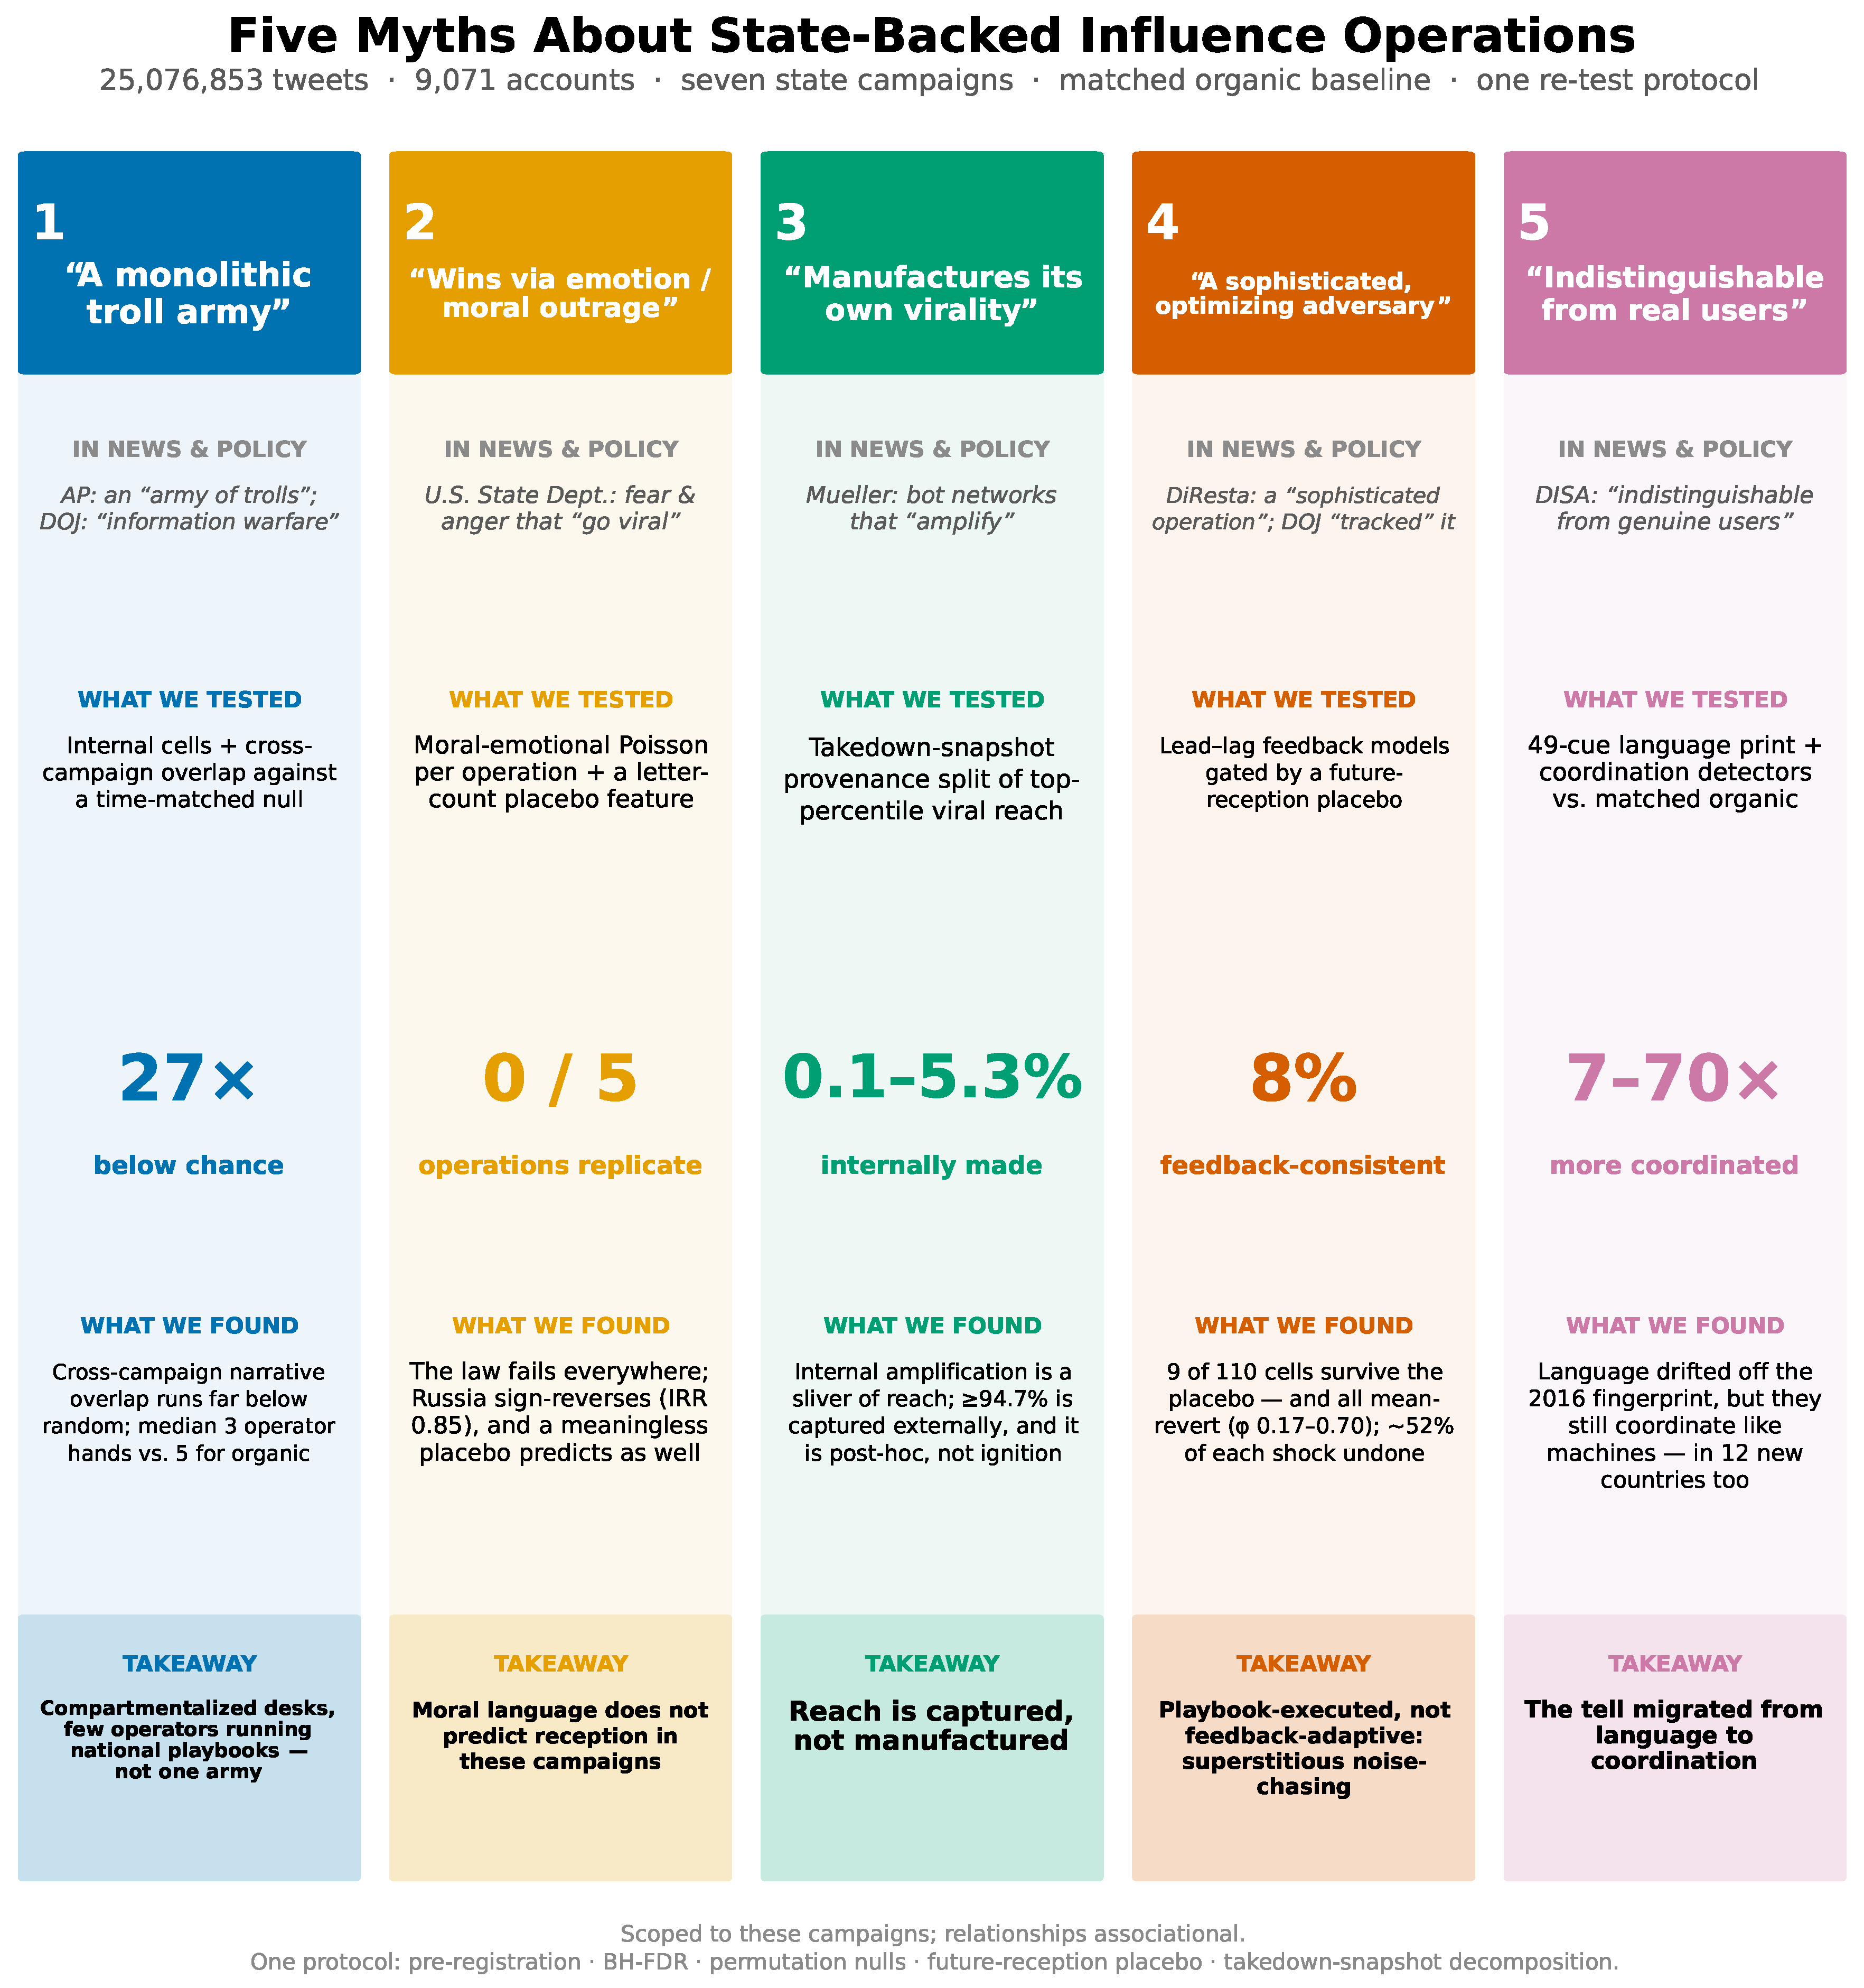
Figure 1 previews each claim, its provenance, the test we apply, and the corrected finding;
Table 1 gives the signature statistics.
Each of these beliefs has a published provenance, and we attach that provenance to each myth rather than debunking a strawman: every section below opens by attributing its claim to at least one peer-reviewed or authoritative source, and wherever possible to a source that makes the claim
about state influence operations specifically rather than about social media or human psychology in general. The point is not that these sources are careless. It is that the claims were, for the most part, established on evidence that cannot by itself separate a genuine signal from a measurement artifact: single campaigns rather than portfolios, the manipulation arm with no organic comparison, statistical significance on enormous samples reported without placebos or false-discovery control, and a near-total absence of re-testing. Beyond the scholarly provenance, each belief also circulates as received wisdom in journalism and policy reporting;
Appendix A catalogues representative statements of each myth across authoritative news outlets and government, intelligence, and policy-institution documents.
We assemble
complete archives (not samples) of seven government-documented influence campaigns released through the Twitter Information Operations program: 25,076,853 tweets posted by 9071 accounts attributed to operations linked to Russia, Iran, Venezuela, and Bangladesh, spanning 2009–2018. We pair these with a matched organic-user baseline drawn from an independent release of same-country, same-period accounts that were never taken down [
1]. Against this evidence base, we re-test each of the five claims under a single, pre-registered common protocol described in
Section 3. Where a claim was originally established on the manipulation arm alone, we re-establish it as a contrast against real users; where it rested on uncorrected significance, we apply false-discovery control and permutation nulls; and, where it could be confounded by trend or regression-to-the-mean, we introduce placebo features that a genuine effect must beat.
Three cautions bound every claim in this paper. First, our evidence concerns these specific, already-investigated campaigns; we make no claim about influence operations that platforms never caught, and “these operations do not do X” is never “no influence operation does X.” Second, all reported relationships are associational: we describe what co-occurs, never what causes what. Where a verb such as “manufactures,” “learns,” or “optimizes” appears in a myth title or a quoted source, it belongs to the folk claim under test, not to our own analytic vocabulary. Third, several widely believed patterns turn out not to hold in these campaigns’ data; showing this does not make the campaigns harmless. On the contrary, several of the corrected findings describe a more efficient adversary than the folk picture suggests, not a less consequential one.
This paper makes four contributions. First, we re-test five recurring claims about influence operations at portfolio scale, anchored to a matched organic baseline and under a pre-registered protocol; each claim weakens or reverses when scoped to these campaigns. Second, we replace the folk picture with an internally coherent account of these operations as compartmentalized, thinly staffed content factories whose viral reach is captured from an external audience rather than internally generated. Third, we document a reusable methodological lesson: on a corpus of confirmed manipulation, significance testing without baselines, placebos, or false-discovery control reproduces the very patterns analysts expect to find, so that only matched baselines, placebo features, and pre-registration separate a genuine regularity from a measurement artifact. Fourth, we replicate the corrected regularities out-of-sample on twelve further country-groups, establishing that they are cross-national rather than idiosyncratic to the original four countries.
4. Myth 1: “A Monolithic Troll Army”
In popular and policy discourse, the “troll factory” is imagined as a single, unified army acting in concert (
Appendix A). The foundational scholarship is in fact more specific: Linvill and Warren, analyzing the IRA’s English-language activity, describe an
industrial operation “mass produced from a system of interchangeable parts, where each class of part fulfilled a specialized function,” identifying distinct handle categories [
2]. The myth, then, is the popular reading of “troll factory” as one undifferentiated mass; the published account already points toward specialization. Recent network studies reinforce this reading: coordinated communities decompose into behavioral archetypes rather than a single mass [
3,
4], while reported coordination among separate operations [
6] weakens once proper baselines are applied [
7]. Our task is to measure that compartmentalization directly and ask what it implies about how the factory is staffed.
We reconstruct each operation’s internal structure from co-activity, shared-infrastructure, and content-overlap networks, validating recovered cells against a degree-preserving rewiring null. We then measure the cross-campaign overlap of narratives, domains, and external retweet targets against a time-matched null and, as a production-side capstone, estimate how many distinct authorial “hands” sit behind each desk [
62] using a joint stylometric-and-behavioral clustering with the number of operators selected by prediction strength and bracketed by bootstrap. Three terms recur and are defined here. A
desk is a coordination-recovered cluster of accounts: a validated cell of the fused coordination network, reported at eight or more active accounts. A
hand is a distinct authorial signature within a desk, recovered by jointly clustering per-account style features (language-aware function-word frequencies, punctuation and emoji rates, lexical diversity, message-length statistics) and behavioral features (posting-client mix, burstiness, inter-tweet timing, diurnal rhythm). The operator estimate
is the largest number of clusters whose split-half prediction strength [
63] reaches
, bracketed by a 50-draw account-level bootstrap;
Appendix B specifies the features, algorithm, and selection rule in full.
The operations are not one army; they are
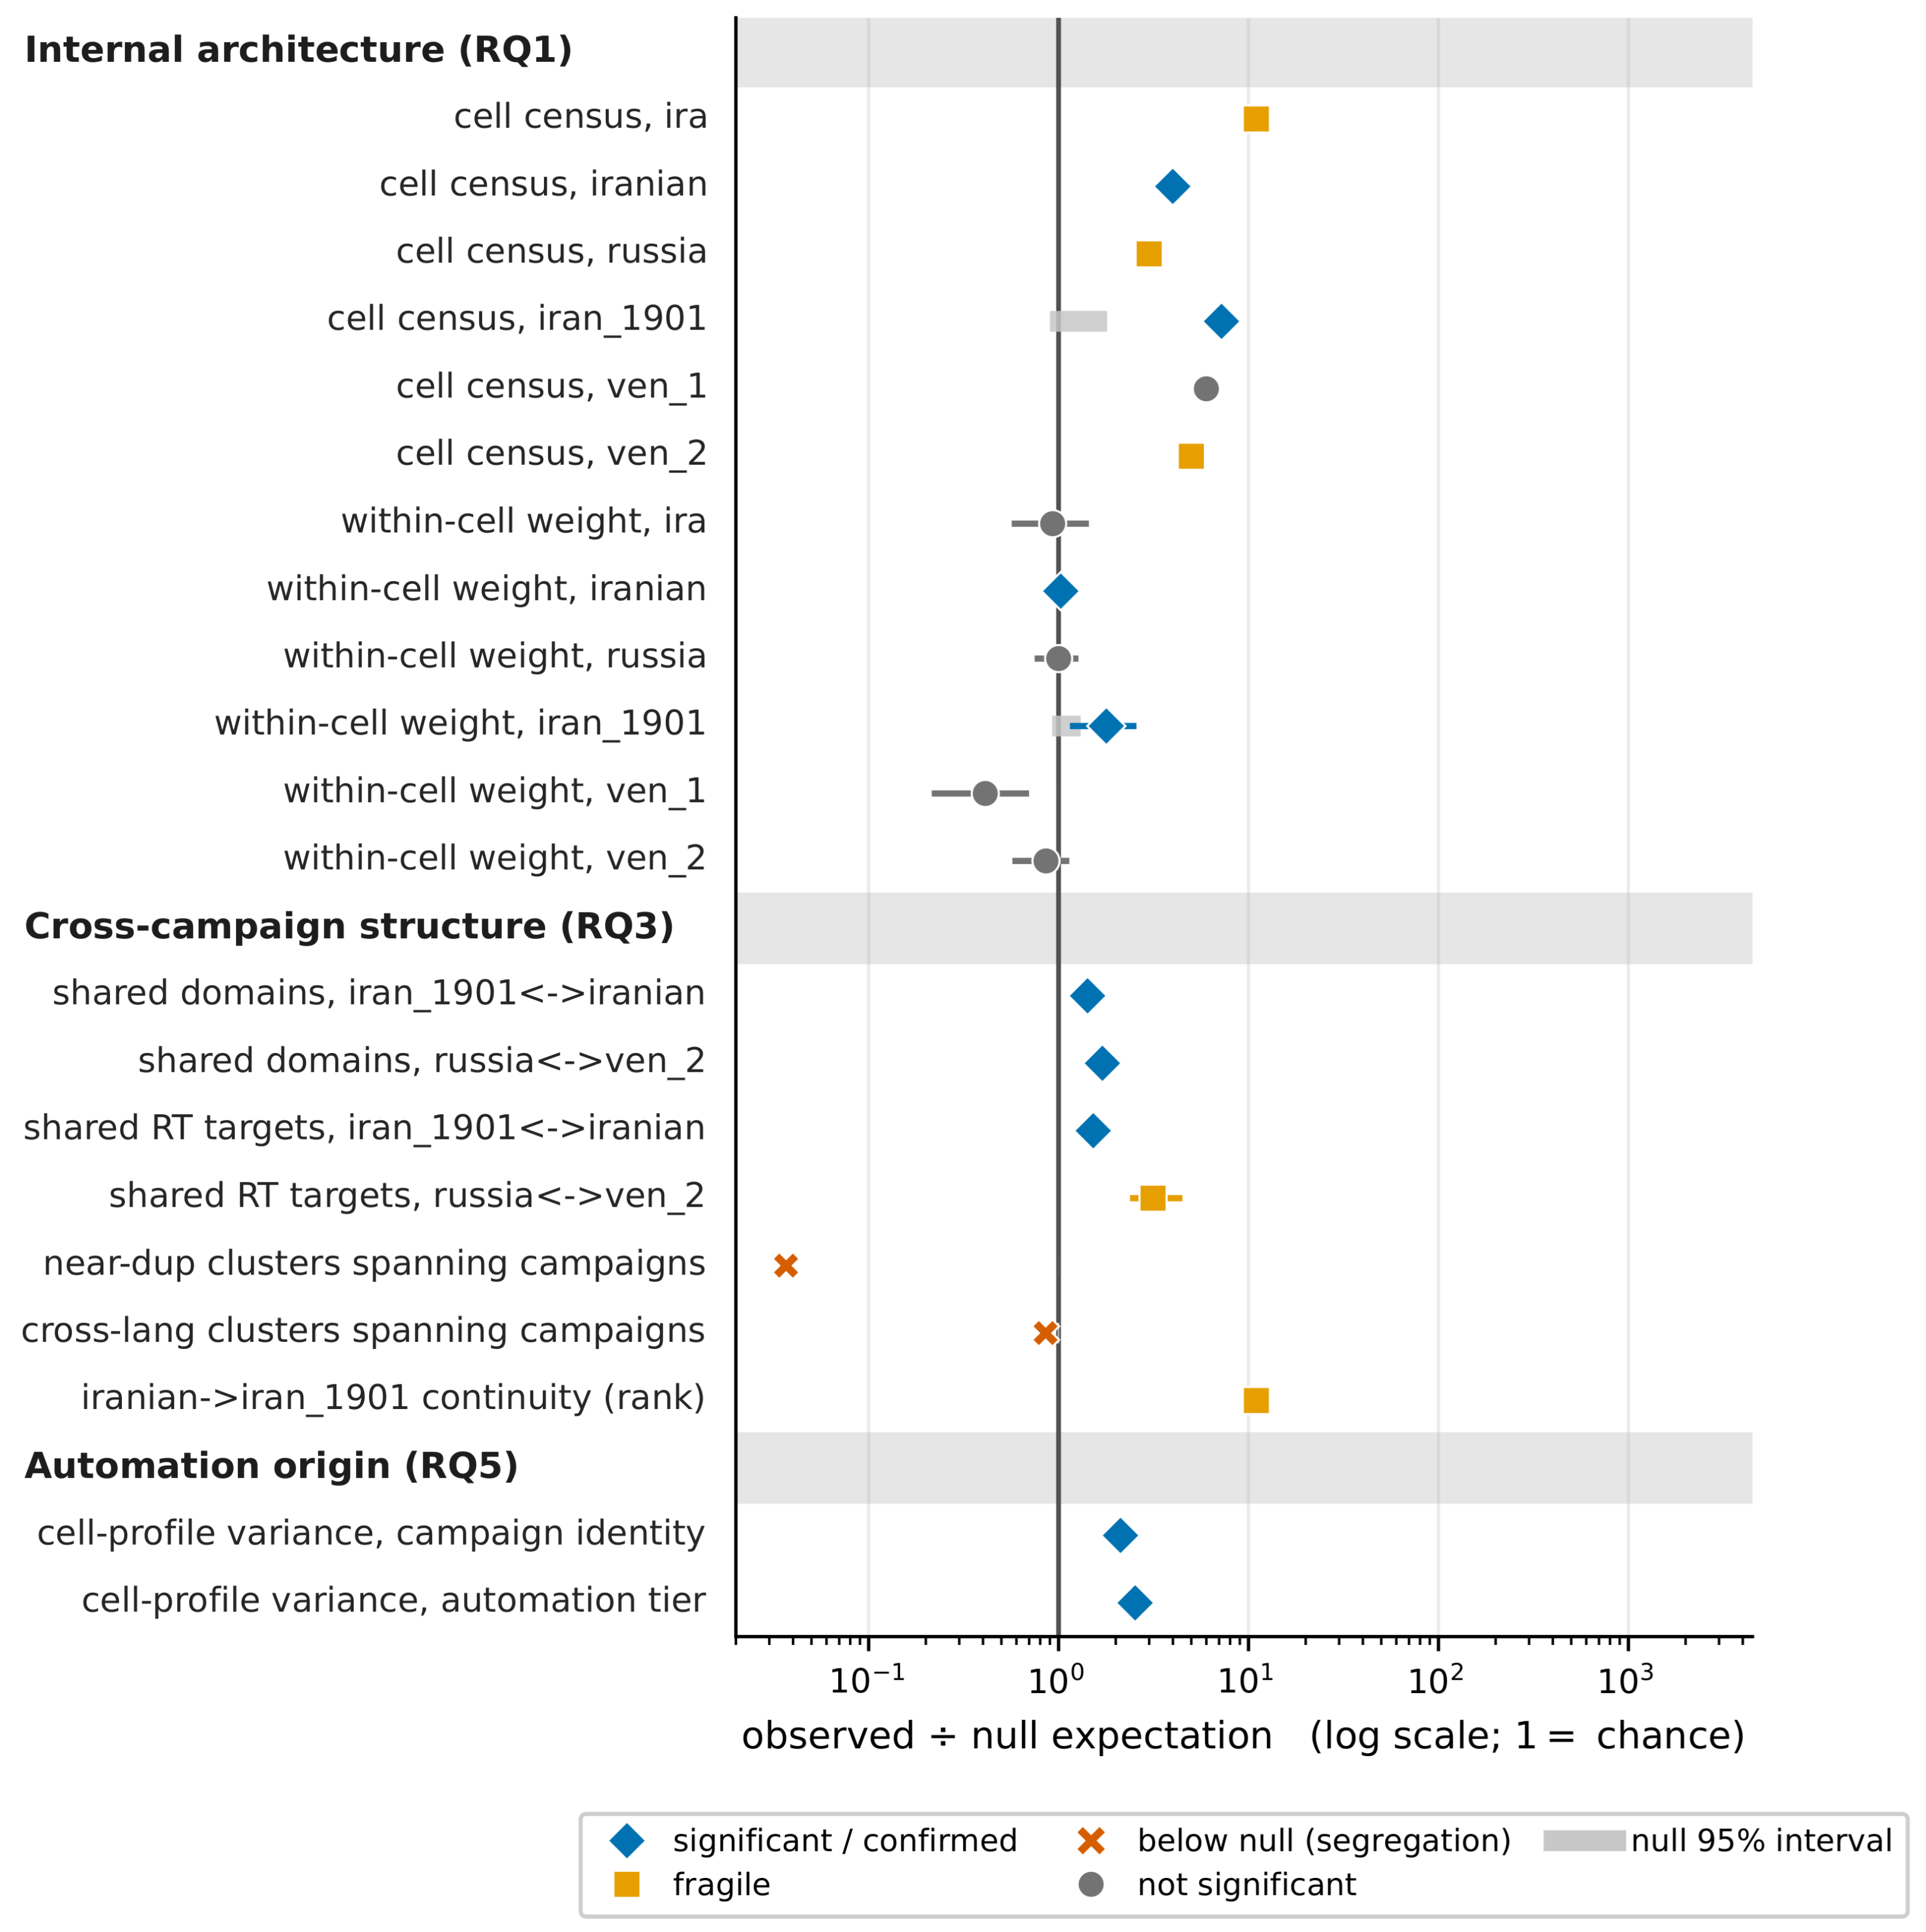
narratively segregated desks, and the segregation is far below chance. Across the portfolio, cross-campaign near-duplicate narrative spanning is observed at 39,113 shared clusters against a time-matched null of roughly 1,064,682, a lift of
, i.e., about
below chance (
Figure 2). Operations share narratives, domains, and external targets
less than random pairs would: 12 of 21 campaign pairs share fewer domains, and 14 of 21 fewer external retweet targets, than popularity-matched chance. The internal topology is national-playbook-specific: the Iranian operations are genuinely cellular (one resolves into eight language-aligned consensus cells); the IRA is a single dominant fabric concealing a 569-account Russian-language retweet desk that is Cyrillic-dominant (Cliff’s
), distinct in client mix (Jensen–Shannon divergence
against a null maximum of
,
), yet keeps the same office-hour rhythm as the English side, i.e., one organization running parallel desks. The only reliable cross-campaign link is between the two Iranian operations (shared-domain lift
,
; shared external-target lift
; six bespoke clients exclusive to the pair). And campaign identity explains roughly twice as much cell-feature variance as automation level (adjusted
vs.
): the desks are campaign-shaped first, automation-shaped second.
Behind these large multi-account desks sit notably few operators. A joint style-and-behavior clustering returns a single stable signature (
) for 20 of 33 analyzable desks, with every desk at
; the two largest IRA desks (1249 and 1100 active accounts) and the largest Venezuelan desks each collapse to a single hand. Because short, multilingual tweets under-individuate authors (the same pipeline collapses
organic accounts too), the defensible comparison is the absolute operator count at matched sample size: IO desks carry a median of 3 distinct hands versus 5 for comparable organic crowds (one-sided Mann–Whitney
). A synthetic positive control confirms the estimator tends to
over-split, making “few hands” a conservative reading. Staffing density is itself playbook-specific (a ~
spread): the scripted IRA and Venezuelan fabrics show the fewest hands per account, the cellular Iranian operations the most. A neural authorship-style representation (LUAR content-independent embeddings) [
64], computed independently on the same desks, reproduces the collapse and is if anything sharper (24 of 33 desks at a single neural signature; median one hand in both arms); the two representations agree at the aggregate level but not on the precise per-desk count (Spearman
), so we report “hands” as a
range, not a headcount.
An independent line of evidence, based on personnel records rather than platform data, supports this staffing picture. Poliakoff and Toepfl analyze 350 curricula vitae that former IRA staff self-published on Russia’s two main job-search platforms between 2013 and 2021 [
65]. Their sample is cumulative and organization-wide (the authors state that their data “allow no conclusions about the absolute numbers” of the workforce, and treat 350 as an undercount); its modal role is “content manager” (
,
of the sample), the organization resembles a mid-sized media or PR company with a five-level hierarchy, and only
of workers explicitly reported using English at work, with the small foreign-targeting departments explicitly untraceable in the CV data. These figures reconcile with ours once the estimands are aligned: a cumulative payroll of hundreds, spread across departments, platforms, shifts, and nine years of turnover, is consistent with our finding that any one Twitter-facing desk was authored by a few
concurrent hands, because our
counts concurrently distinguishable authorial signatures per desk, not the organization’s headcount. Their observation that English-capable staff formed a small sliver of the payroll independently corroborates the thin staffing that our stylometric collapse recovers for the English-language desk.
Because Linvill and Warren assigned each IRA account to a functional category
by hand [
2], their labels furnish an external check on desks we recovered from coordination and style with no access to those labels. Matching their public account-category release to the IRA arm by screen name returns a role for 2604 of our IRA accounts (91.6% of their distinctly labeled handles; the shortfall concentrates in the RightTroll category, consistent with its heavier suspension and handle turnover). The hand labels fall
along our recovered structure rather than across it (
Table 4). The two giant single-hand desks split by language exactly as the manual categories do: the Russian-language desk (giant hand #2) is essentially entirely NonEnglish, while the English-language desk (giant hand #1) absorbs all four English functional categories—RightTroll, LeftTroll, HashtagGamer, and Fearmonger. Two readings follow. First, a desk reconstructed without the hand labels reproduces the first cut an independent team drew manually. Second, and more consequentially, that single English desk is one
stylometric hand yet co-hosts all four English categories: the much-discussed handle “types” are job functions resident in a single authoring desk, not separate armies—real at the level of content function, collapsed at the level of authorship. The lone partial exception, NewsFeed (automated headline-amplifier accounts), sits mostly in smaller desks, consistent with a low-coordination feed function rather than a manned role. This check is confirmatory and IRA-only—no comparable external hand-labeling exists for the other operations—and alters no primary estimate.
These operations are compartmentalized productions run by few operators executing national playbooks, not a unified army. This finding extends rather than contradicts the specialization Linvill and Warren first described, and quantifies just how thinly the factory is staffed.
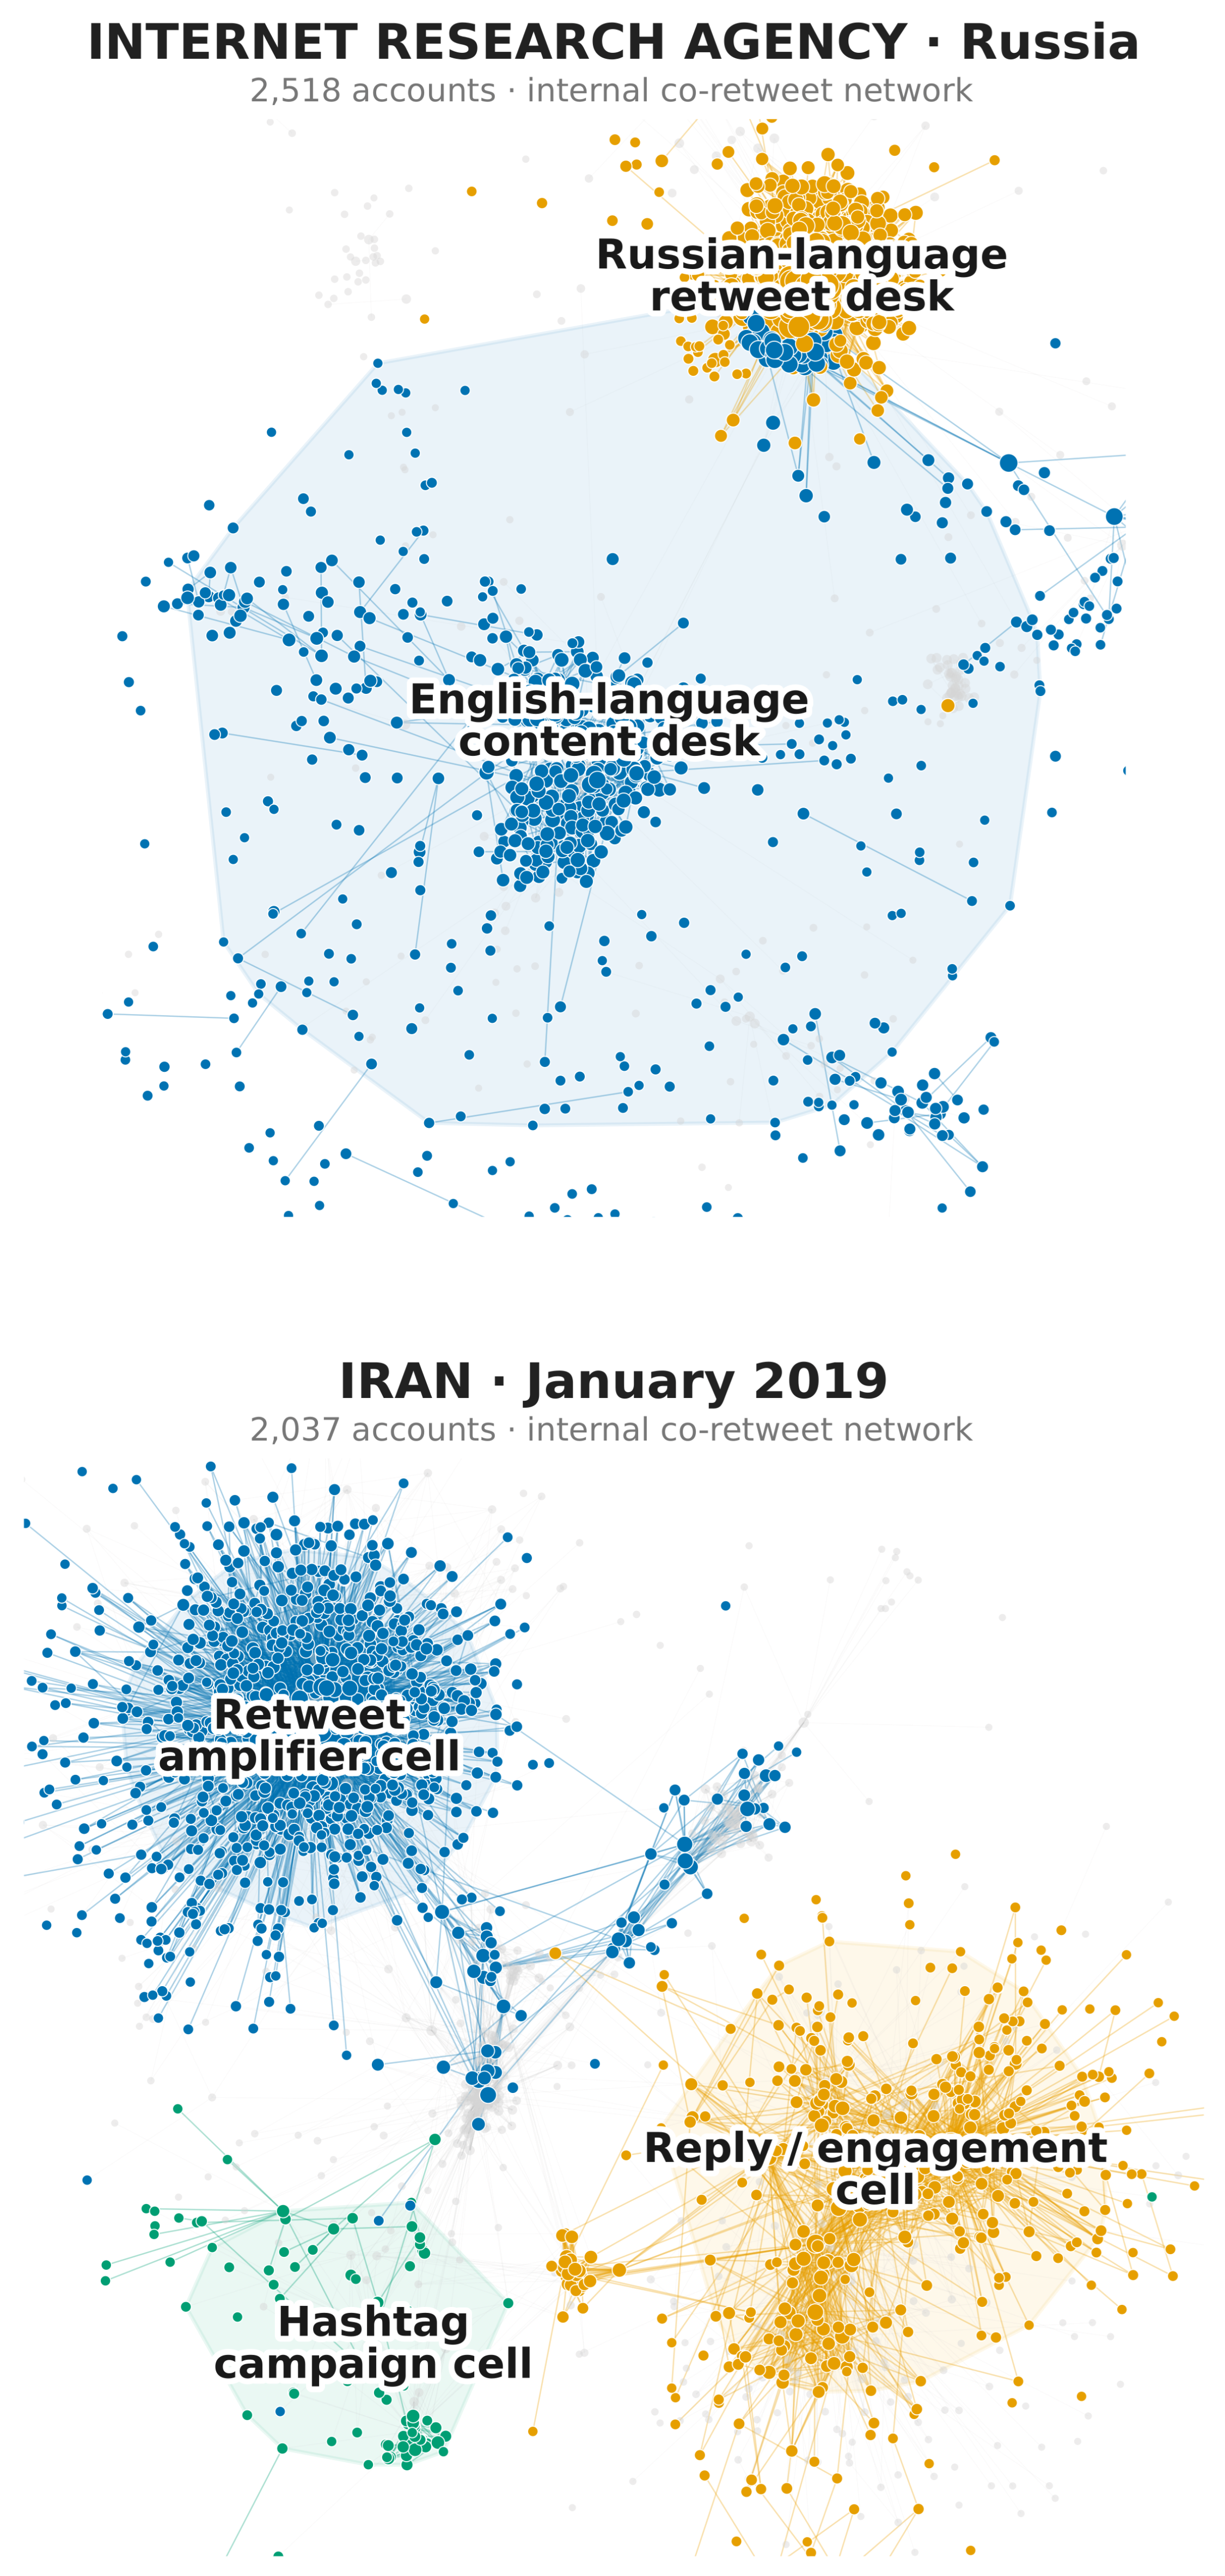
Figure 3 renders this compartmentalization directly for the two largest operations. Each node is an account and each edge a within-operation co-retweet; node color marks the largest coordination desks the clustering recovers, and node size scales with within-operation degree. The IRA (top) is a single dense fabric that nonetheless braids two co-equal desks: a low-retweet, hashtag-driven English-language content desk and a high-retweet, link-amplifying Russian-language desk—the same D0/D1 division that the Linvill–Warren overlay in
Table 4 independently labels English versus non-English. Iran (January 2019, bottom) instead resolves into functionally distinct cells—a retweet-amplifier cell, a reply/engagement cell, and a hashtag-campaign cell—rather than one undifferentiated mass. The two operations are wired along visibly different national playbooks, yet each is a compartmentalized production floor of specialized desks rather than a unified army; the contrast between a single braided fabric and a set of separated cells is exactly the national-playbook specificity the cell statistics report.
5. Myth 2: “Wins via Emotion/Moral Outrage”
Having established what the factory
is, we turn to what it produces and whether that content earns attention. The general principle is Brady and colleagues’ moral-contagion law: in organic networks, each added moral-emotional word is associated with substantially greater diffusion [
8], an effect whose expression is itself amplified by social-feedback learning [
9]. The belief that this law drives influence operations has been instantiated directly on real troll data: analyzing the released IRA Twitter corpus, Suk and colleagues report that “negative tweets had 1.206 times the rate of retweets than those without negative sentiment” [
16], and the policy literature describes the operations as engineering emotionally resonant memes and human-interest content for spread [
26] (
Appendix A). There is also independent reason for caution: Burton, Cruz, and Hahn show that the contagion model can perform no better than an implausible alternative [
10], precisely the fragility we test for inside state propaganda. A large pre-registered replication and meta-analysis by the original authors likewise finds the effect positive but small and heterogeneous, even reversing sign in one corpus [
11], while adjacent work locates the engagement lever in out-group animosity [
12] and negativity [
14] rather than in moral-emotional content as such.
On the 16,459,645 original (non-retweet) tweets in the corpus, we fit the moral-emotional reception model per operation, never pooled. The moral-emotional predictor is the per-tweet count of matches against the moral-emotional word list of Brady and colleagues [
8], standardized per standard deviation; the engagement outcome is the tweet’s external retweet count (the snapshot retweet counter net of retweets by the operation’s own accounts), with like counts as a co-primary outcome (the Russian hub, whose like and retweet counters collapse to near-identity, is read on likes). The model is a fixed-effects Poisson regression with account and year fixed effects, controls for tweet age, URL/hashtag/mention presence, automation decile, near-duplicate cluster size, and standard errors clustered by account; each estimate is reported across a nine-specification curve (three covariate sets crossed with three outlier-trimming rules).
Appendix B gives the full specification. We report two moral-foundations dictionaries side-by-side, never averaged because they genuinely diverge (mean Spearman
), and, critically, an
XYZ letter-count placebo: the count of occurrences of the letters x, y, and z in the tweet text (after removing URLs and mentions), standardized identically and entered into the identical model. This deliberately meaningless feature, introduced by Burton and colleagues in their re-analysis of the moral-contagion evidence [
10], is the test’s diagnostic instrument: it has no plausible psychological mechanism, so if it earns an engagement coefficient comparable to or larger than the moral-emotional feature on the same sample, a positive moral-emotional coefficient cannot be read as evidence of moral contagion; it shows instead that, at this corpus size, baseline-free significance attaches even to noise.
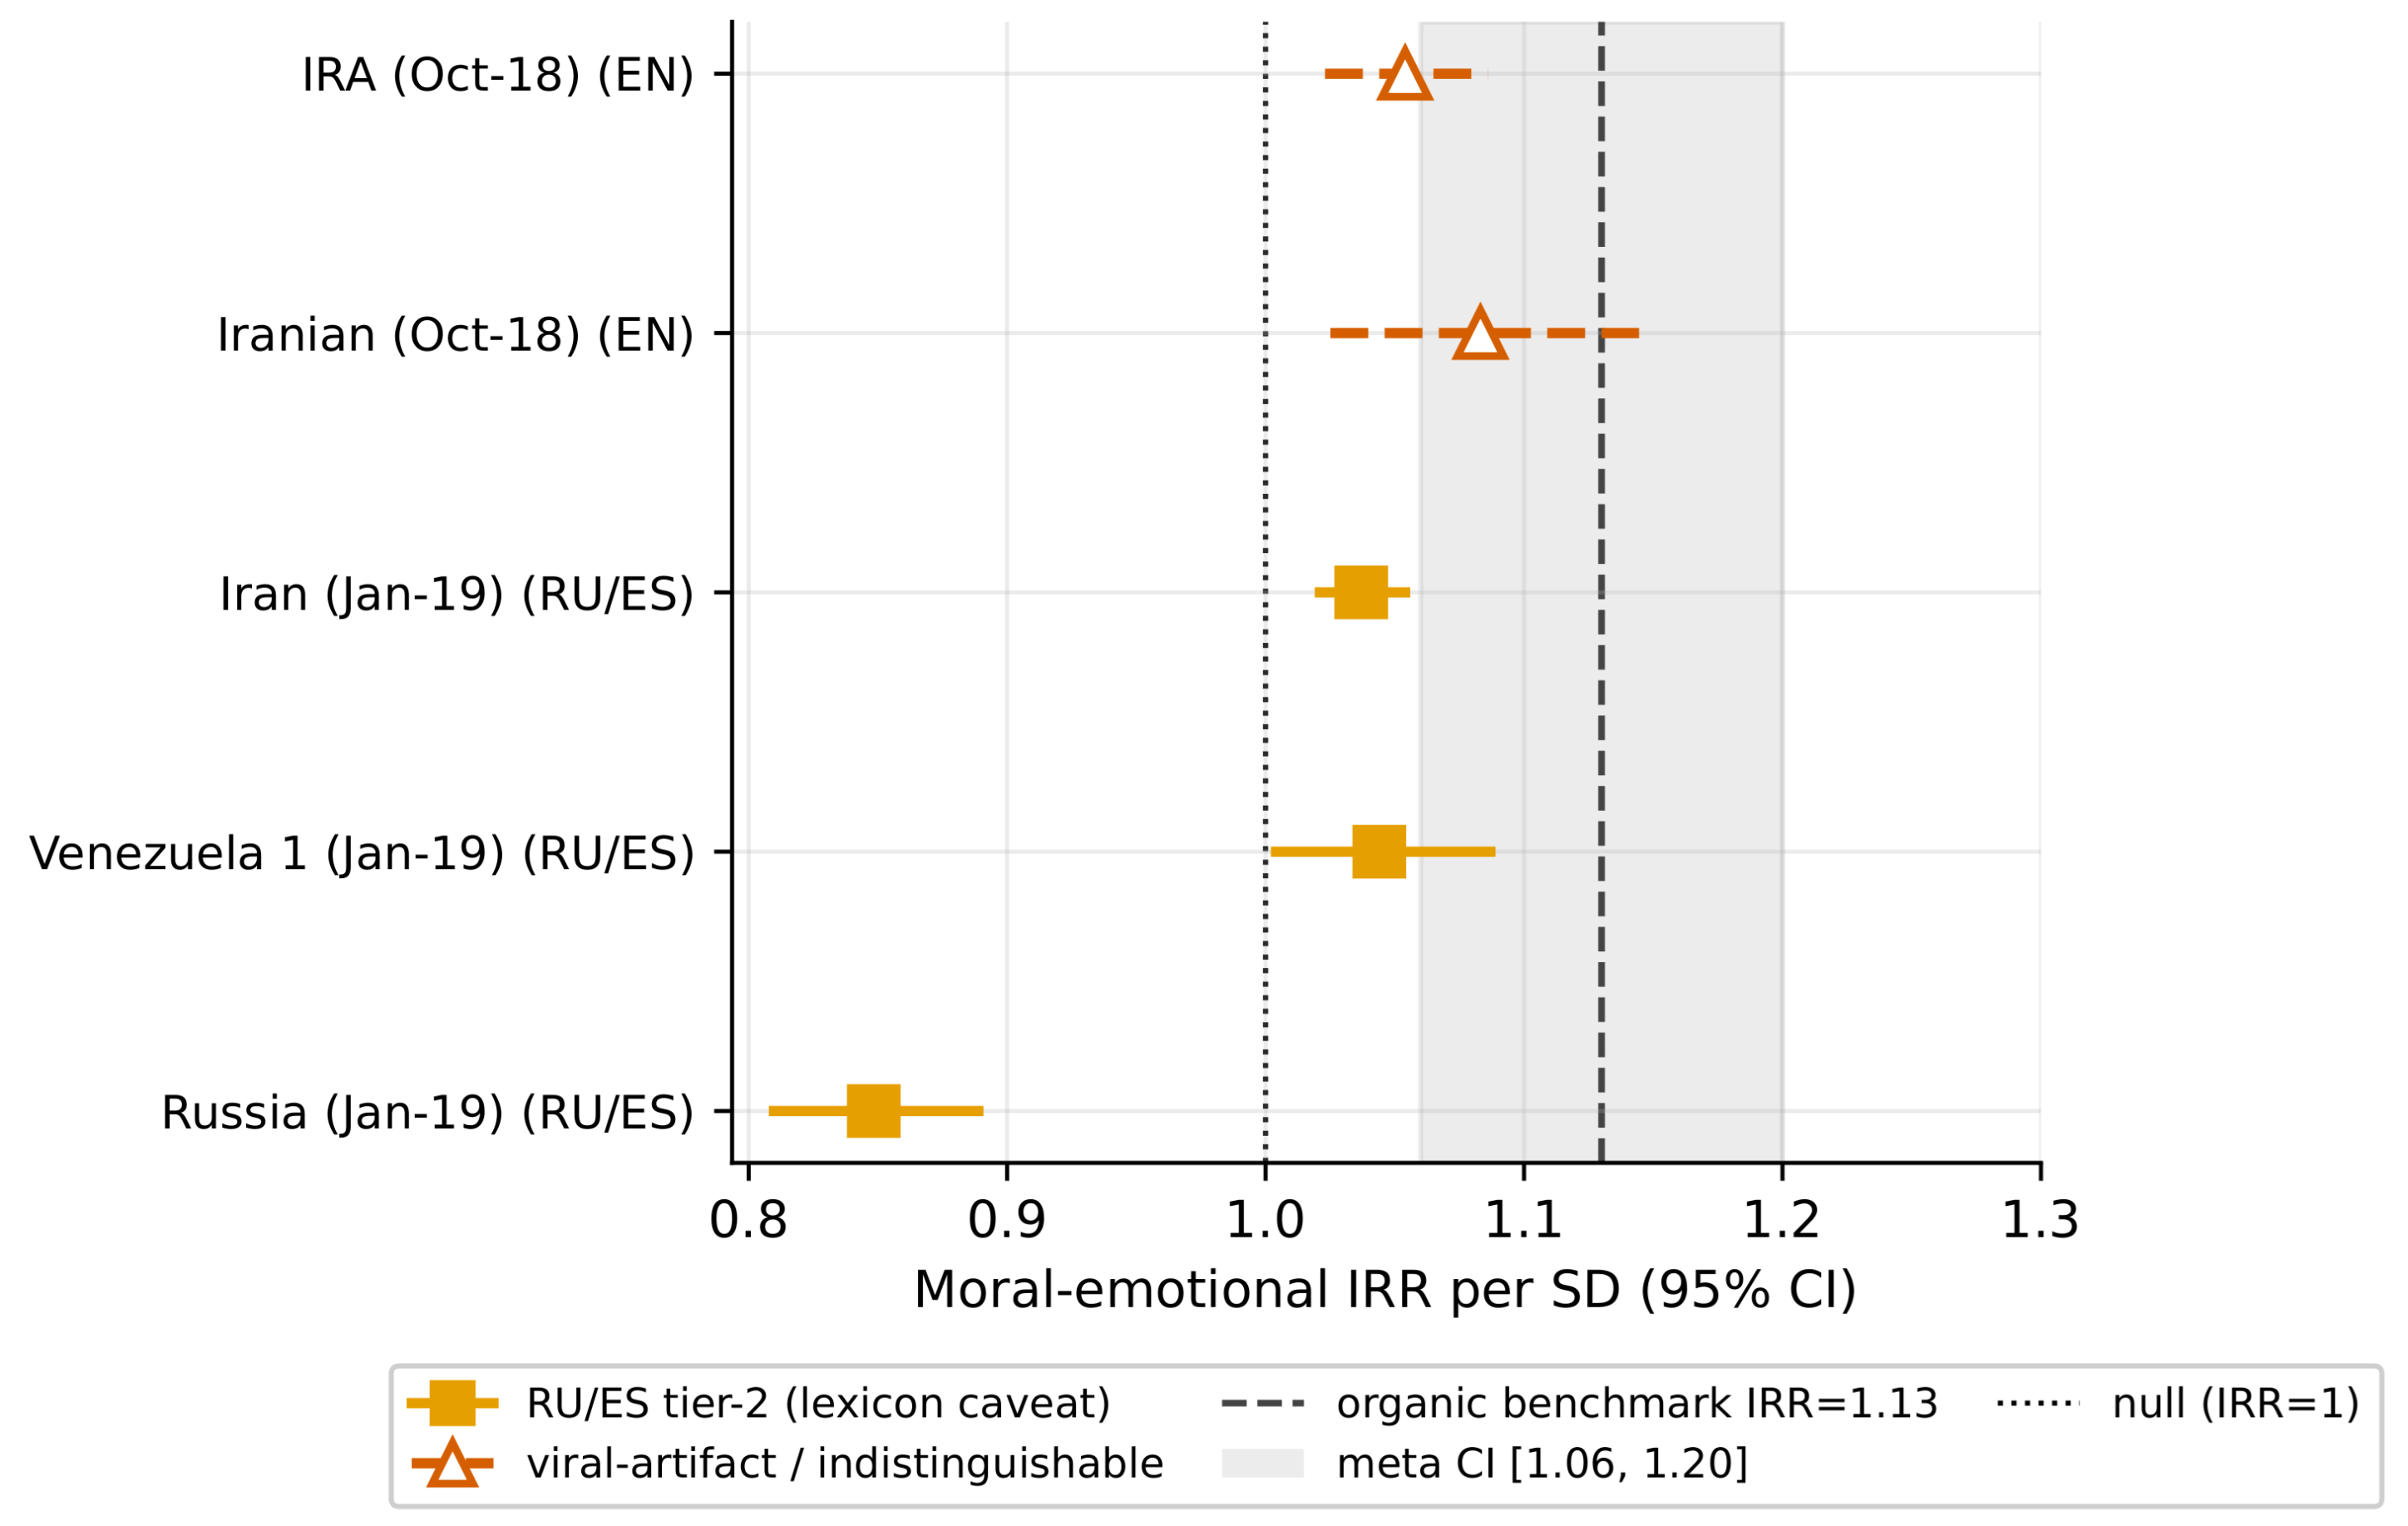
The organic moral-contagion law does not replicate in any operation (
Figure 4). Against an organic anchor incidence-rate ratio (IRR) of about
, the Russian operation
sign-reverses: moral-emotional wording is associated with
less engagement net of persona (IRR
, 95% CI
, 0 of 9 specifications positive), while its XYZ letter-count placebo is strongly positive (
). The corpus manufactures a spurious positive effect for a meaningless feature even where morality is genuinely negative. The Iranian (Oct-2018) operation’s moral effect (IRR
,
) is statistically
indistinguishable from its XYZ letter-count placebo (
,
). The remaining operations are weakly positive but below the organic anchor and outside its confidence interval (Iran
, Venezuela
), or at the reception floor. This is the “large-corpus mirage” Burton and colleagues warned of, demonstrated inside state propaganda: on samples this large, baseline-free significance attaches to noise.
Moral-emotional language does not predict reception
in these campaigns’ data, and a meaningless placeholder predicts as well. This is a claim about these operations and this measurement,
not that affect or morality is irrelevant to virality in general. One methodological caveat distinguishes this myth from the others: because the organic baseline lacks engagement counts (
Section 10), Myth 2 alone is
placebo-anchored rather than baseline-anchored. We do not contrast IO against a like-for-like organic reception model; instead, the XYZ letter-count placebo shows that the apparent moral-emotional effect is not feature-specific: a meaningless placeholder earns the same or larger coefficient on the same samples. That is sufficient to defeat the specific claim (that
morality drives reception in these operations) without resting on a within-corpus positive, but it is a weaker instrument than the matched-baseline contrasts that carry Myths 1, 3, and 5, and we flag it as such. If anything, the prior literature sharpens the result: even the IO-specific instantiation finds sentiment to be one driver among informational and topical ones, with positive sentiment slightly
suppressing retweets [
16], so the belief we test is narrow, and it does not hold here.
6. Myth 3: “Manufactures Its Own Virality”
A central image of influence operations is sockpuppet self-amplification: the operation engineers its own viral ignition (
Appendix A). This mechanism is well-established in the diffusion literature: automated accounts amplify low-credibility content, especially early in a cascade and by targeting influential users [
17], and coordinated accounts can boost a cascade’s reach up to a saturation threshold [
18]. Against this, linked exposure studies find that Russian IRA reach was concentrated among a few partisan users and dwarfed by domestic media, with no measurable attitudinal effect [
23], that differential spread is carried more by human resharing than by automation [
19], that automated accounts are less central to diffusion than verified or high-profile human accounts [
20], and that amplification, where present, often runs through a cross-platform laundering of external media [
51]. The question is how much of these operations’
actual viral reach this internal machinery accounts for.
The decomposition proceeds in four defined steps;
Appendix B states each in full. First,
viral originals are each campaign’s top
of original tweets ranked by external reach (top
and top decile as robustness tiers). Second,
internal amplification is counted directly from the archive’s retweet edges: the number of retweets of that original emitted by the operation’s own released accounts. Third,
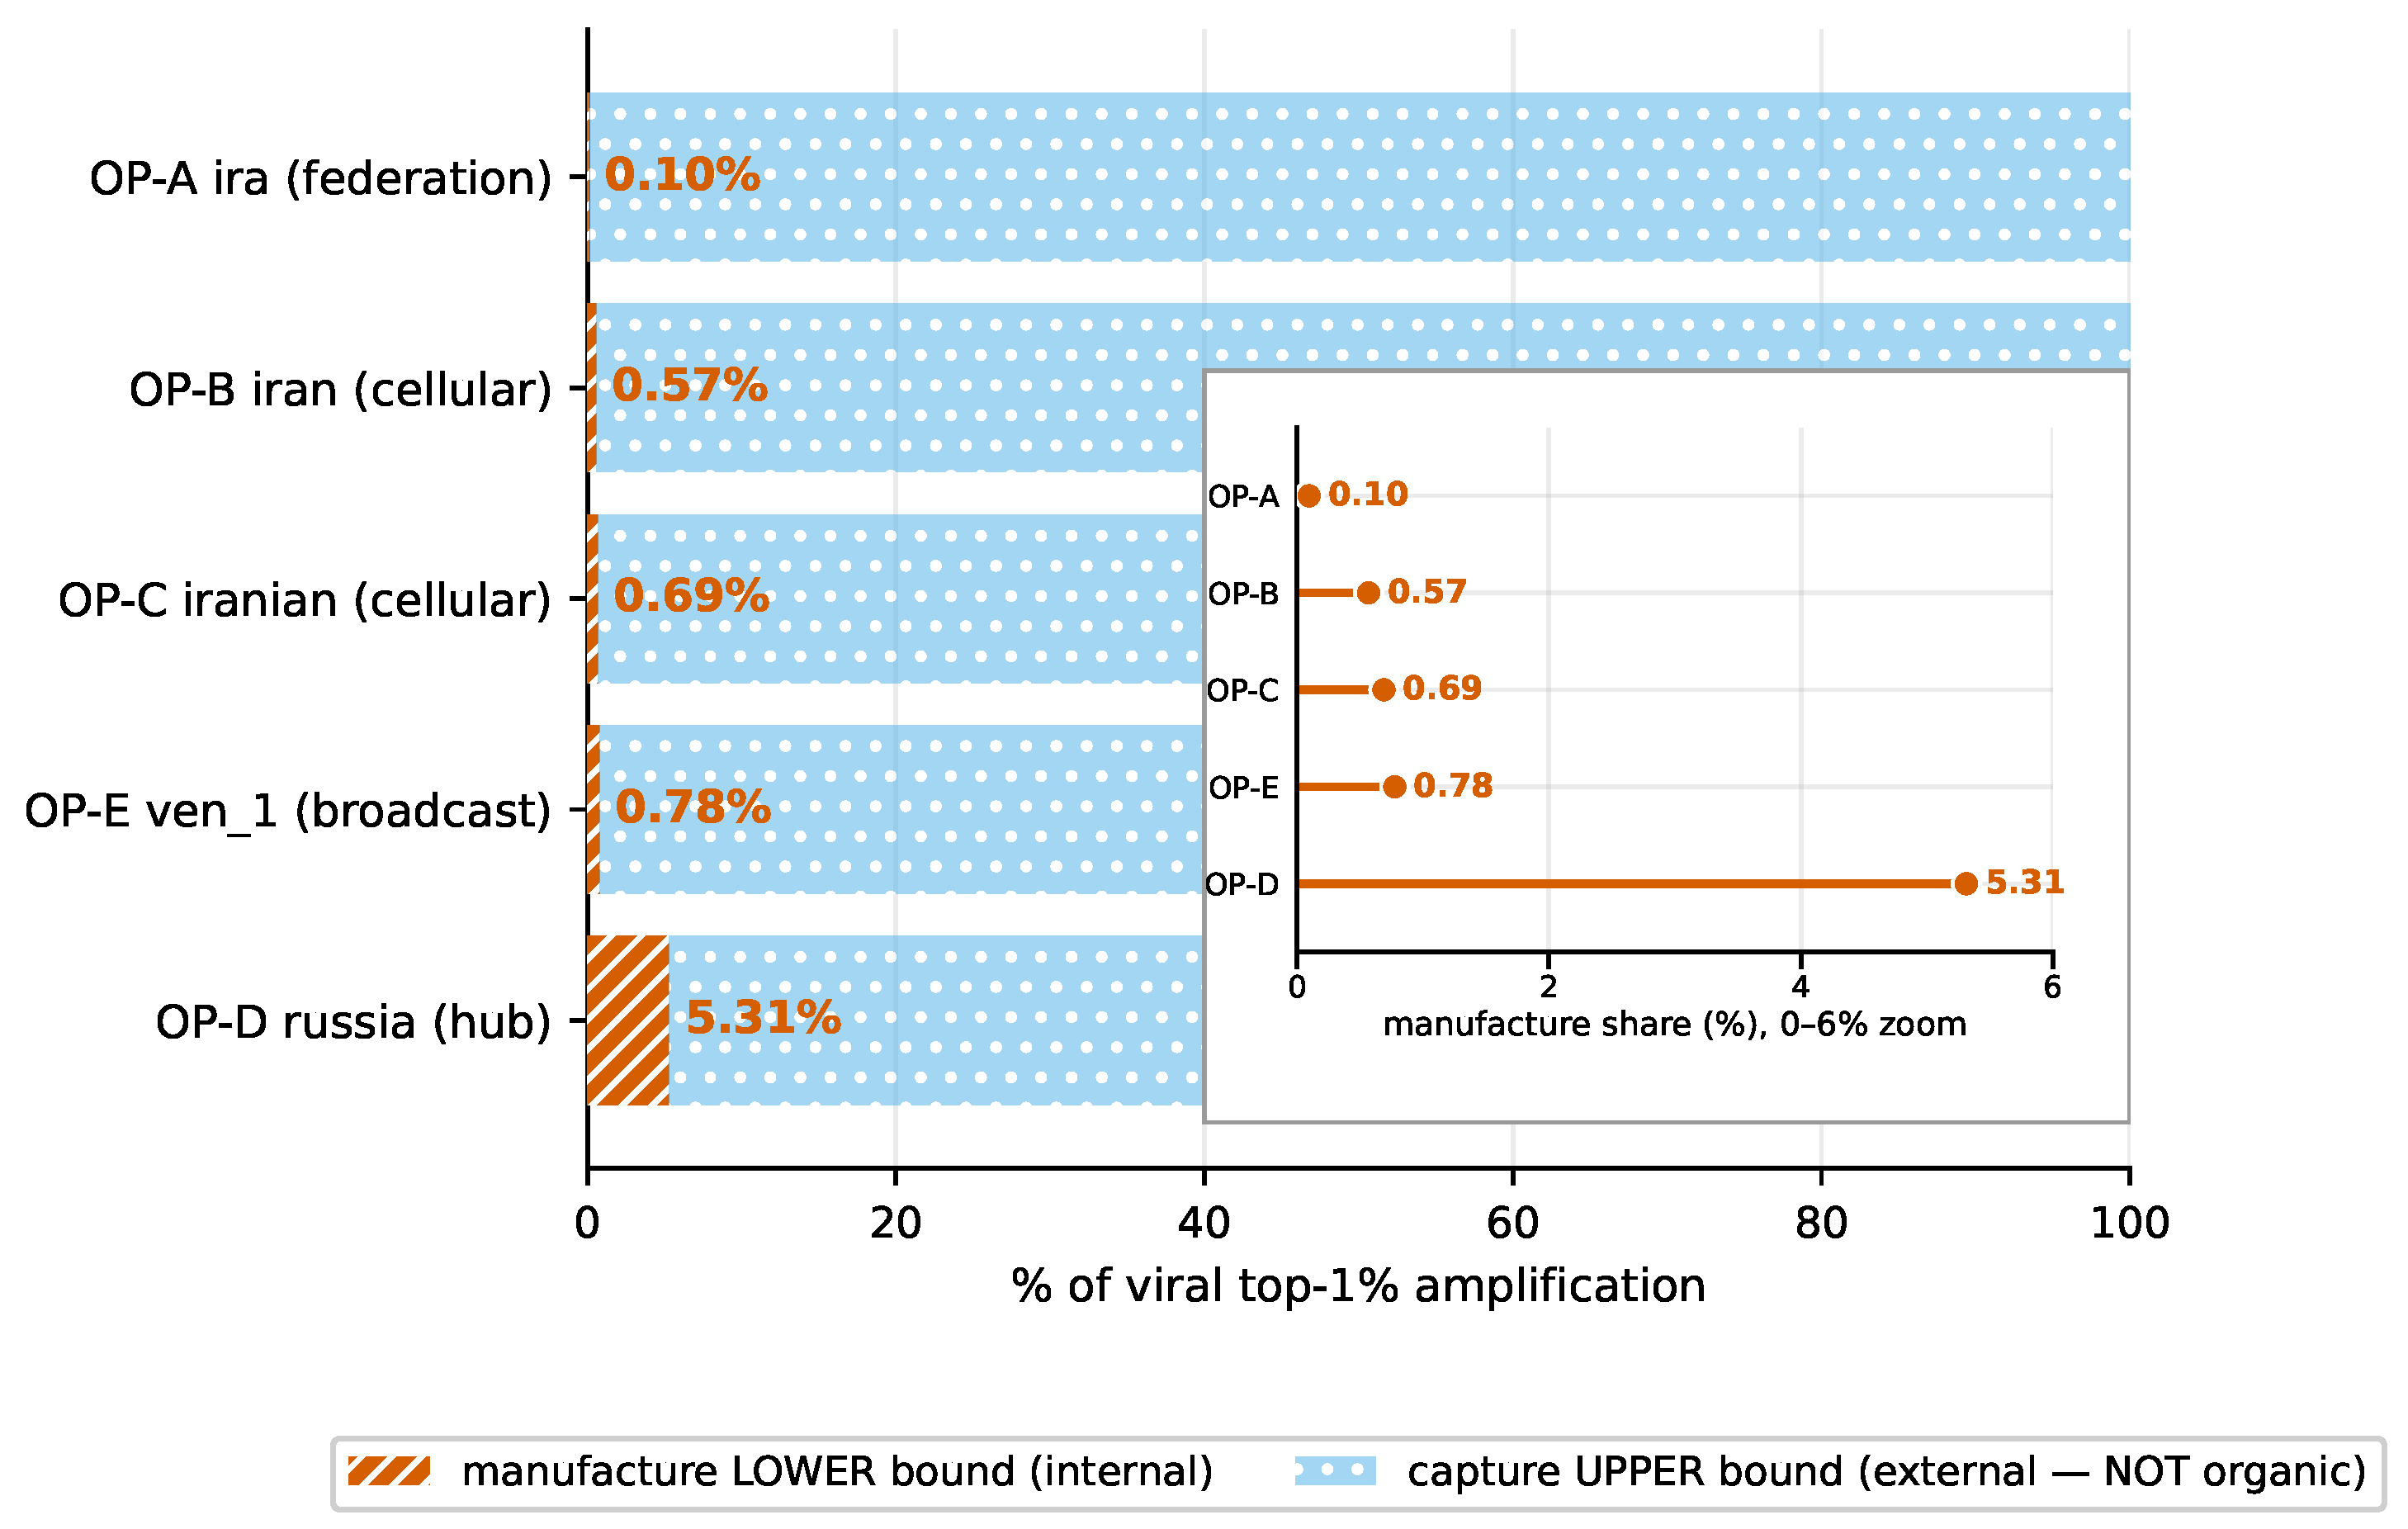
external reach is snapshot-dependent. For the IRA, whose frozen retweet counters reconcile exactly with the archive’s internal retweet edges, external reach is the snapshot counter minus the internal count, a clean subtraction. For the other campaigns, the frozen counters already exclude retweets from co-suspended accounts, so the counter itself serves as an internal-stripped external bound, and subtracting again would double-remove; these external figures are upper bounds on capture and the internal shares are lower bounds on manufacture, and are labeled as such. The
manufactured share of an original is internal amplification over internal-plus-external. Fourth, to ask whether the internal amplification that
is present looks like synchronized ignition or diffuse after-the-fact sharing, we define
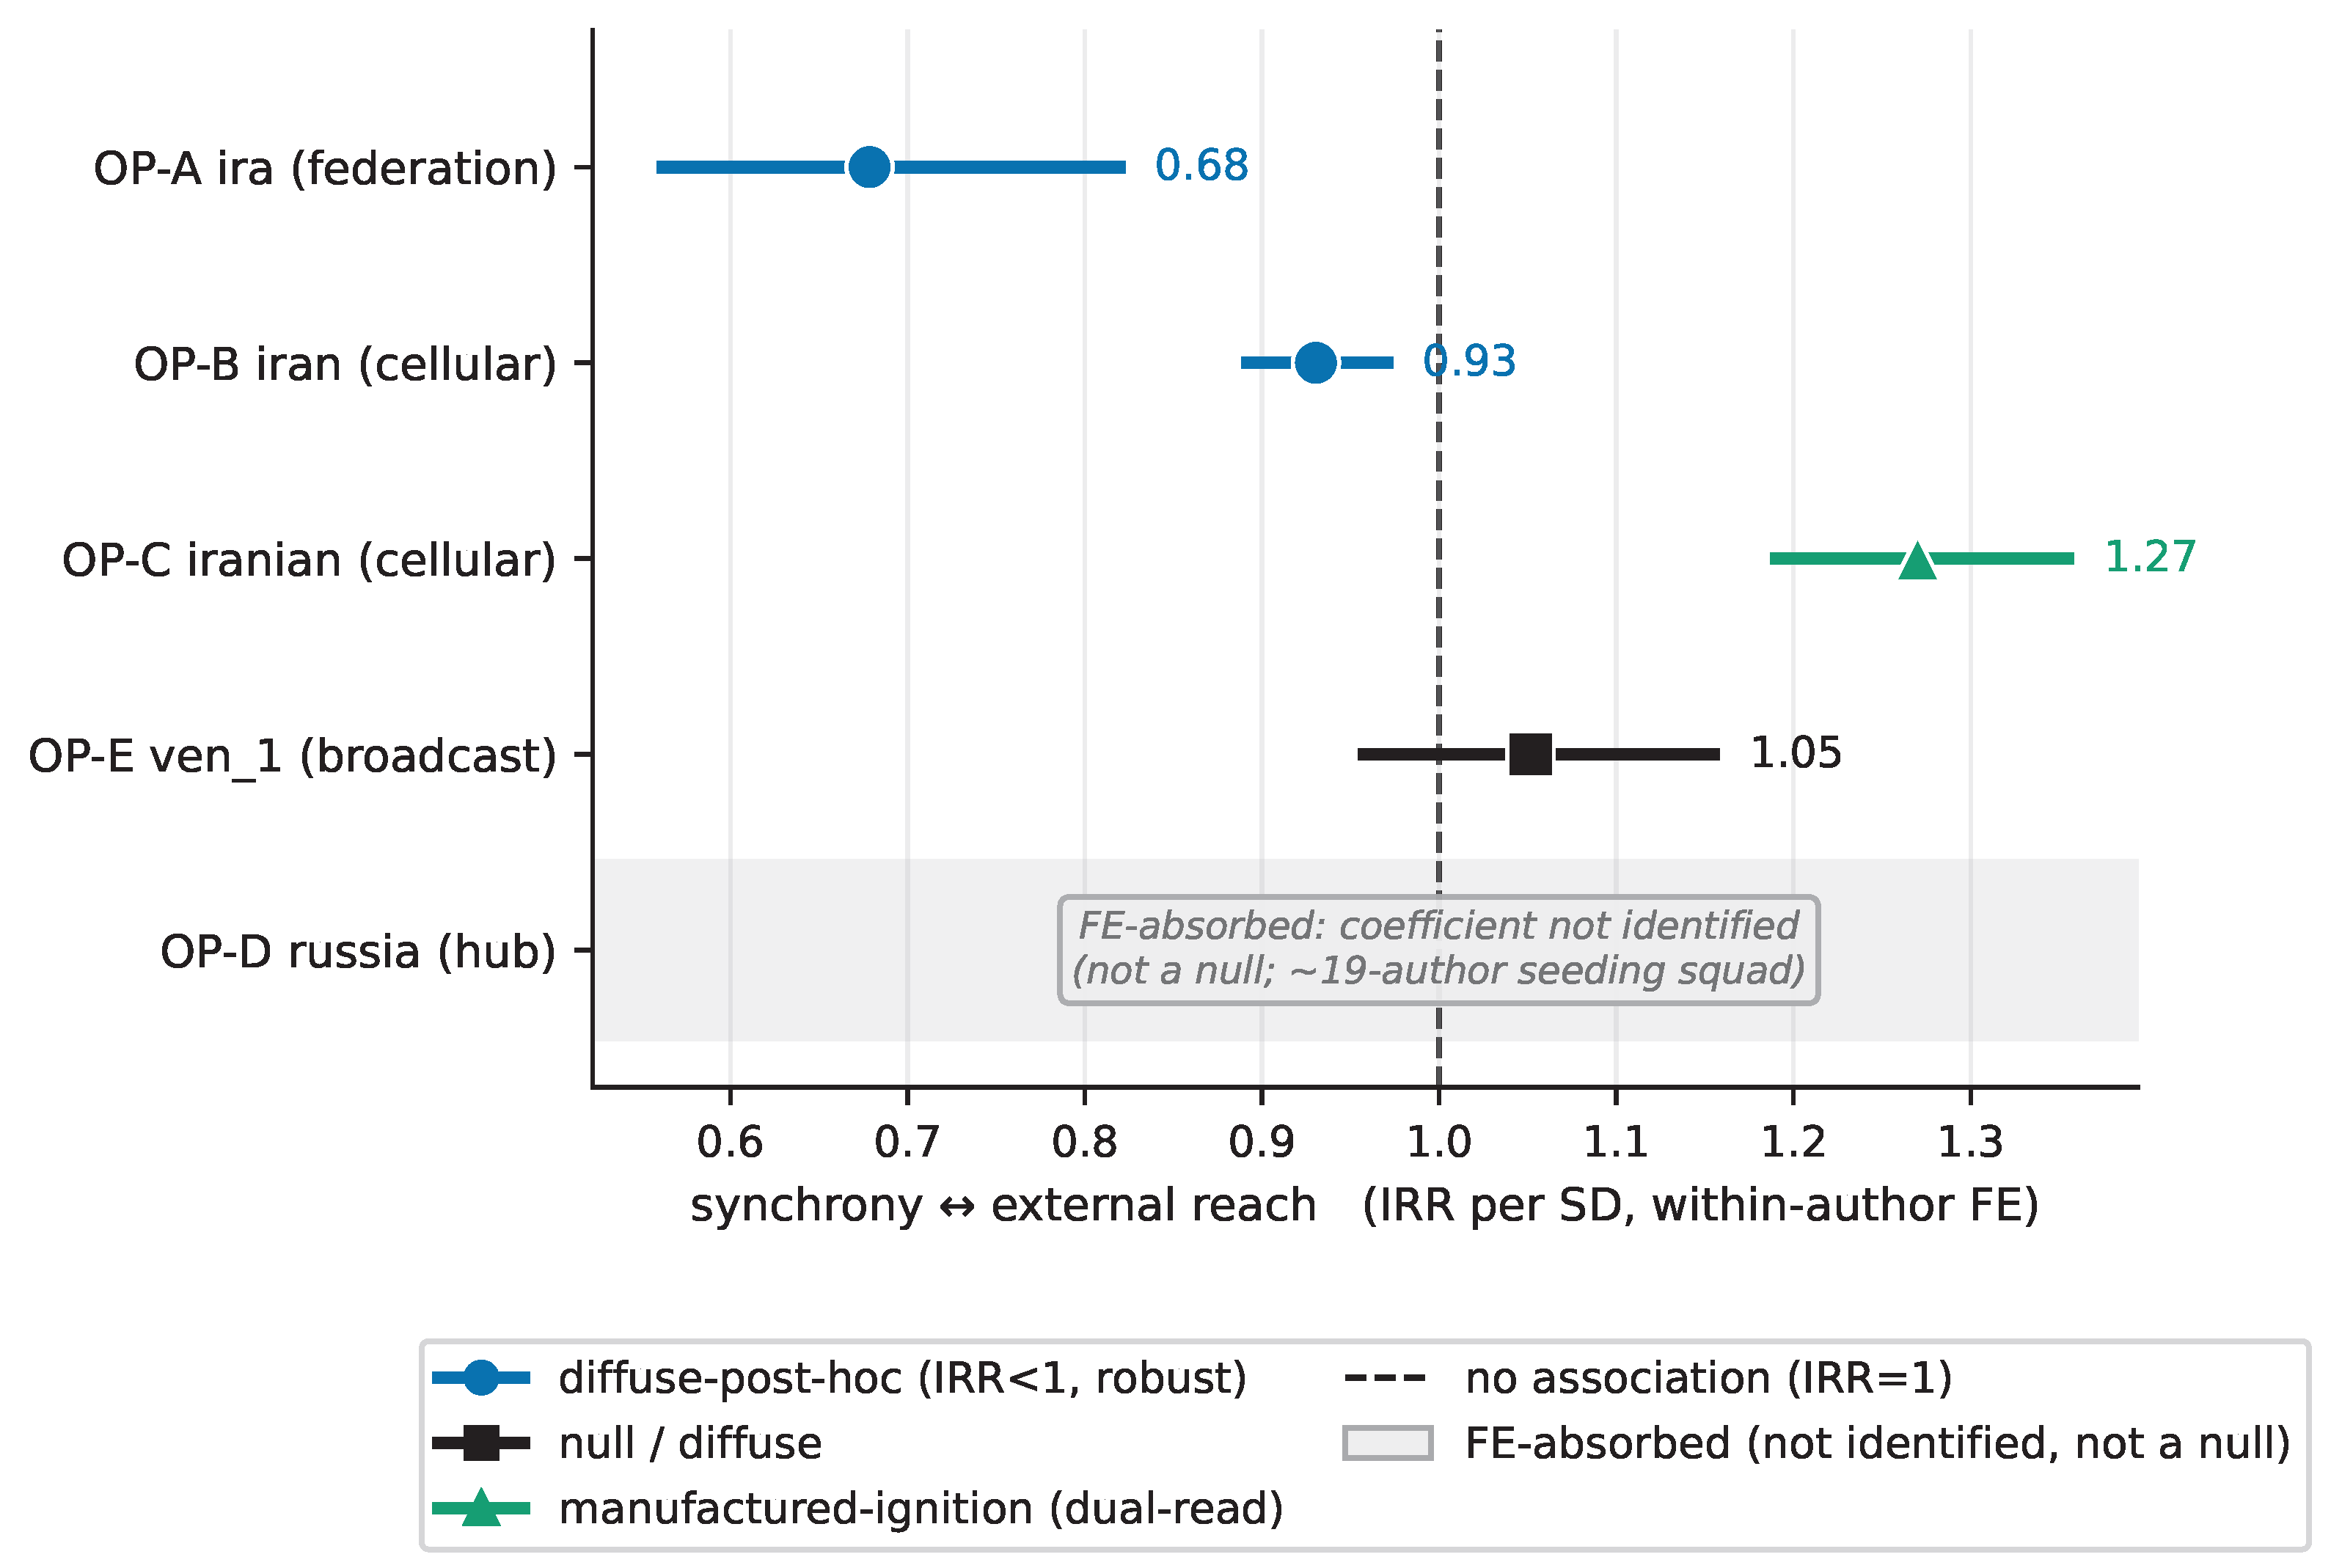
within-author seeding synchrony as the share of an original’s internal retweets that land in a one-minute bucket containing at least two distinct amplifying accounts, and fit a within-author fixed-effects Poisson regression of external reach on this share (standardized per standard deviation, standard errors clustered by account). The pre-registered reading is that a robust positive association is the signature of manufactured ignition, while a negative or null association indicates diffuse post hoc sharing.
Internal manufacture is a small fraction of viral reach (
Figure 5). Across operations, it supplies
(IRA),
(Iran, Jan-2019),
(Iranian, Oct-2018),
(Venezuela-1), and
(the Russian hub) of top-percentile reach; the captured share is therefore ≥99.2% everywhere except the Russian hub (
), while the per-original median manufactured share is 0 in every stratum, consistent with prior findings that the bulk of state-propaganda dissemination is carried by ordinary users rather than the operation’s own accounts [
21], and that dissemination of low-quality content concentrates in a small set of ordinary “supersharer” users [
22]. Internal amplification
is enriched among the winners (
–
), but enrichment is consistent with either manufactured ignition or undetected external coordination, and it does not account for the reach. The enrichment looks like
diffuse post hoc sharing, not synchronized ignition (
Figure 6): within-author seeding synchrony is associated with
fewer external accounts, not more, in the IRA (IRR
,
) and Iran (
,
), null in Venezuela, and positive in only one operation, the confirmed Iranian (Oct-2018) operation (IRR
,
), the lone ignition-like signature. (This ignition result, and the cellular Iranian structure noted under Myth 1, both derive from the operations’ own released archives; the
provisional Iranian mapping noted in
Section 3 concerns only the matched-control contrast of Myth 5, where it is flagged in place.) Within-author seeding synchrony here means same-author co-timed posting; it is distinct from the cross-account same-minute synchrony that distinguishes IO from organic users under Myth 5: the former anti-predicts reach, the latter marks inauthenticity. External reach tracks the
breadth of amplifiers, not their same-minute synchrony. Producer and amplifier roles are distinctly divided by playbook (Cramér’s
, a moderate association), from a 12-account Russian seeding squad to a 717-account Iranian one.
Reach in these operations is
captured, not manufactured, which is not “no reach.” We state the bounding limit plainly and quarantine it in
Section 10: because the archives record only the operations’ own accounts, the external pool cannot be split into genuine organic uptake versus undetected coordination that the corpus sees only the internal tip of. The captured/manufactured contrast holds; the internal composition of the captured share is not resolvable here.
7. Myth 4: “A Sophisticated, Optimizing, Adaptive Adversary”
Having found that reception (Myth 2) and viral reach (Myth 3) lie largely outside these operations’ control, we now ask whether they nonetheless reallocate toward them. The operations are widely described as learning machines that optimize against feedback (
Appendix A). The authoritative policy account portrays the IRA as “run like a sophisticated marketing agency” that “developed their content using digital marketing best practices” [
26], and the doctrine literature calls Russian propaganda “remarkably responsive and nimble” [
25]. The academic literature makes a weaker, temporal claim (that tactics, language, and identities change over time [
27,
28], which we do not dispute), while our own prior work finds trolls act “regardless of the feedback” they receive from genuine users [
29] and that automated accounts lack the time-varying behavioral dynamics that characterize genuine human activity [
30]. Consistent with a scripted reading, a campaign-agnostic classifier across nineteen state operations attributes their detectability to shared, templated tactics [
31], field experiments find no measurable persuasive effect from IRA contact [
24], and even large-language-model microtargeting does not reliably outperform untargeted messaging [
34,
36]. We test the strong belief: do operators reallocate content toward what earns reception?
The design asks a defined question: does a campaign shift its output toward the content classes that earned reception in preceding weeks? The unit of analysis is a
cell: one campaign crossed with one behavior axis and one reception channel (retweets or likes). Eleven behavior axes are tested, spanning surface presentation (URL, hashtag, and mention inclusion; message-length bin; time-of-day; script; language) and content (moral-emotional load; frame, agenda, and target classes), giving 110 feasible operation-level cells. Within each cell, campaign activity is divided into windows (weekly for five campaigns; biweekly for the sparser Russian hub), and the behavior outcome is the prevalence share of each class within its axis and window. The model is a fractional logit regression of next-window prevalence on the class’s
reception rank (the percentile rank of the class’s mean engagement among that window’s classes, a snapshot-robust transform of the frozen counters) at lags one to three, with class fixed effects, an autoregressive prevalence term, and a linear trend; inference uses a permutation null of at least 1000 draws with Benjamini–Hochberg control per campaign and channel. Each cell then passes a pre-registered four-step gate. A cell is
feedback-consistent only if (i) its summed past-reception coefficient is positive and significant against the permutation null, (ii) the model beats an identical specification without the reception terms, and (iii) the future-reception placebo separates: the coefficient on
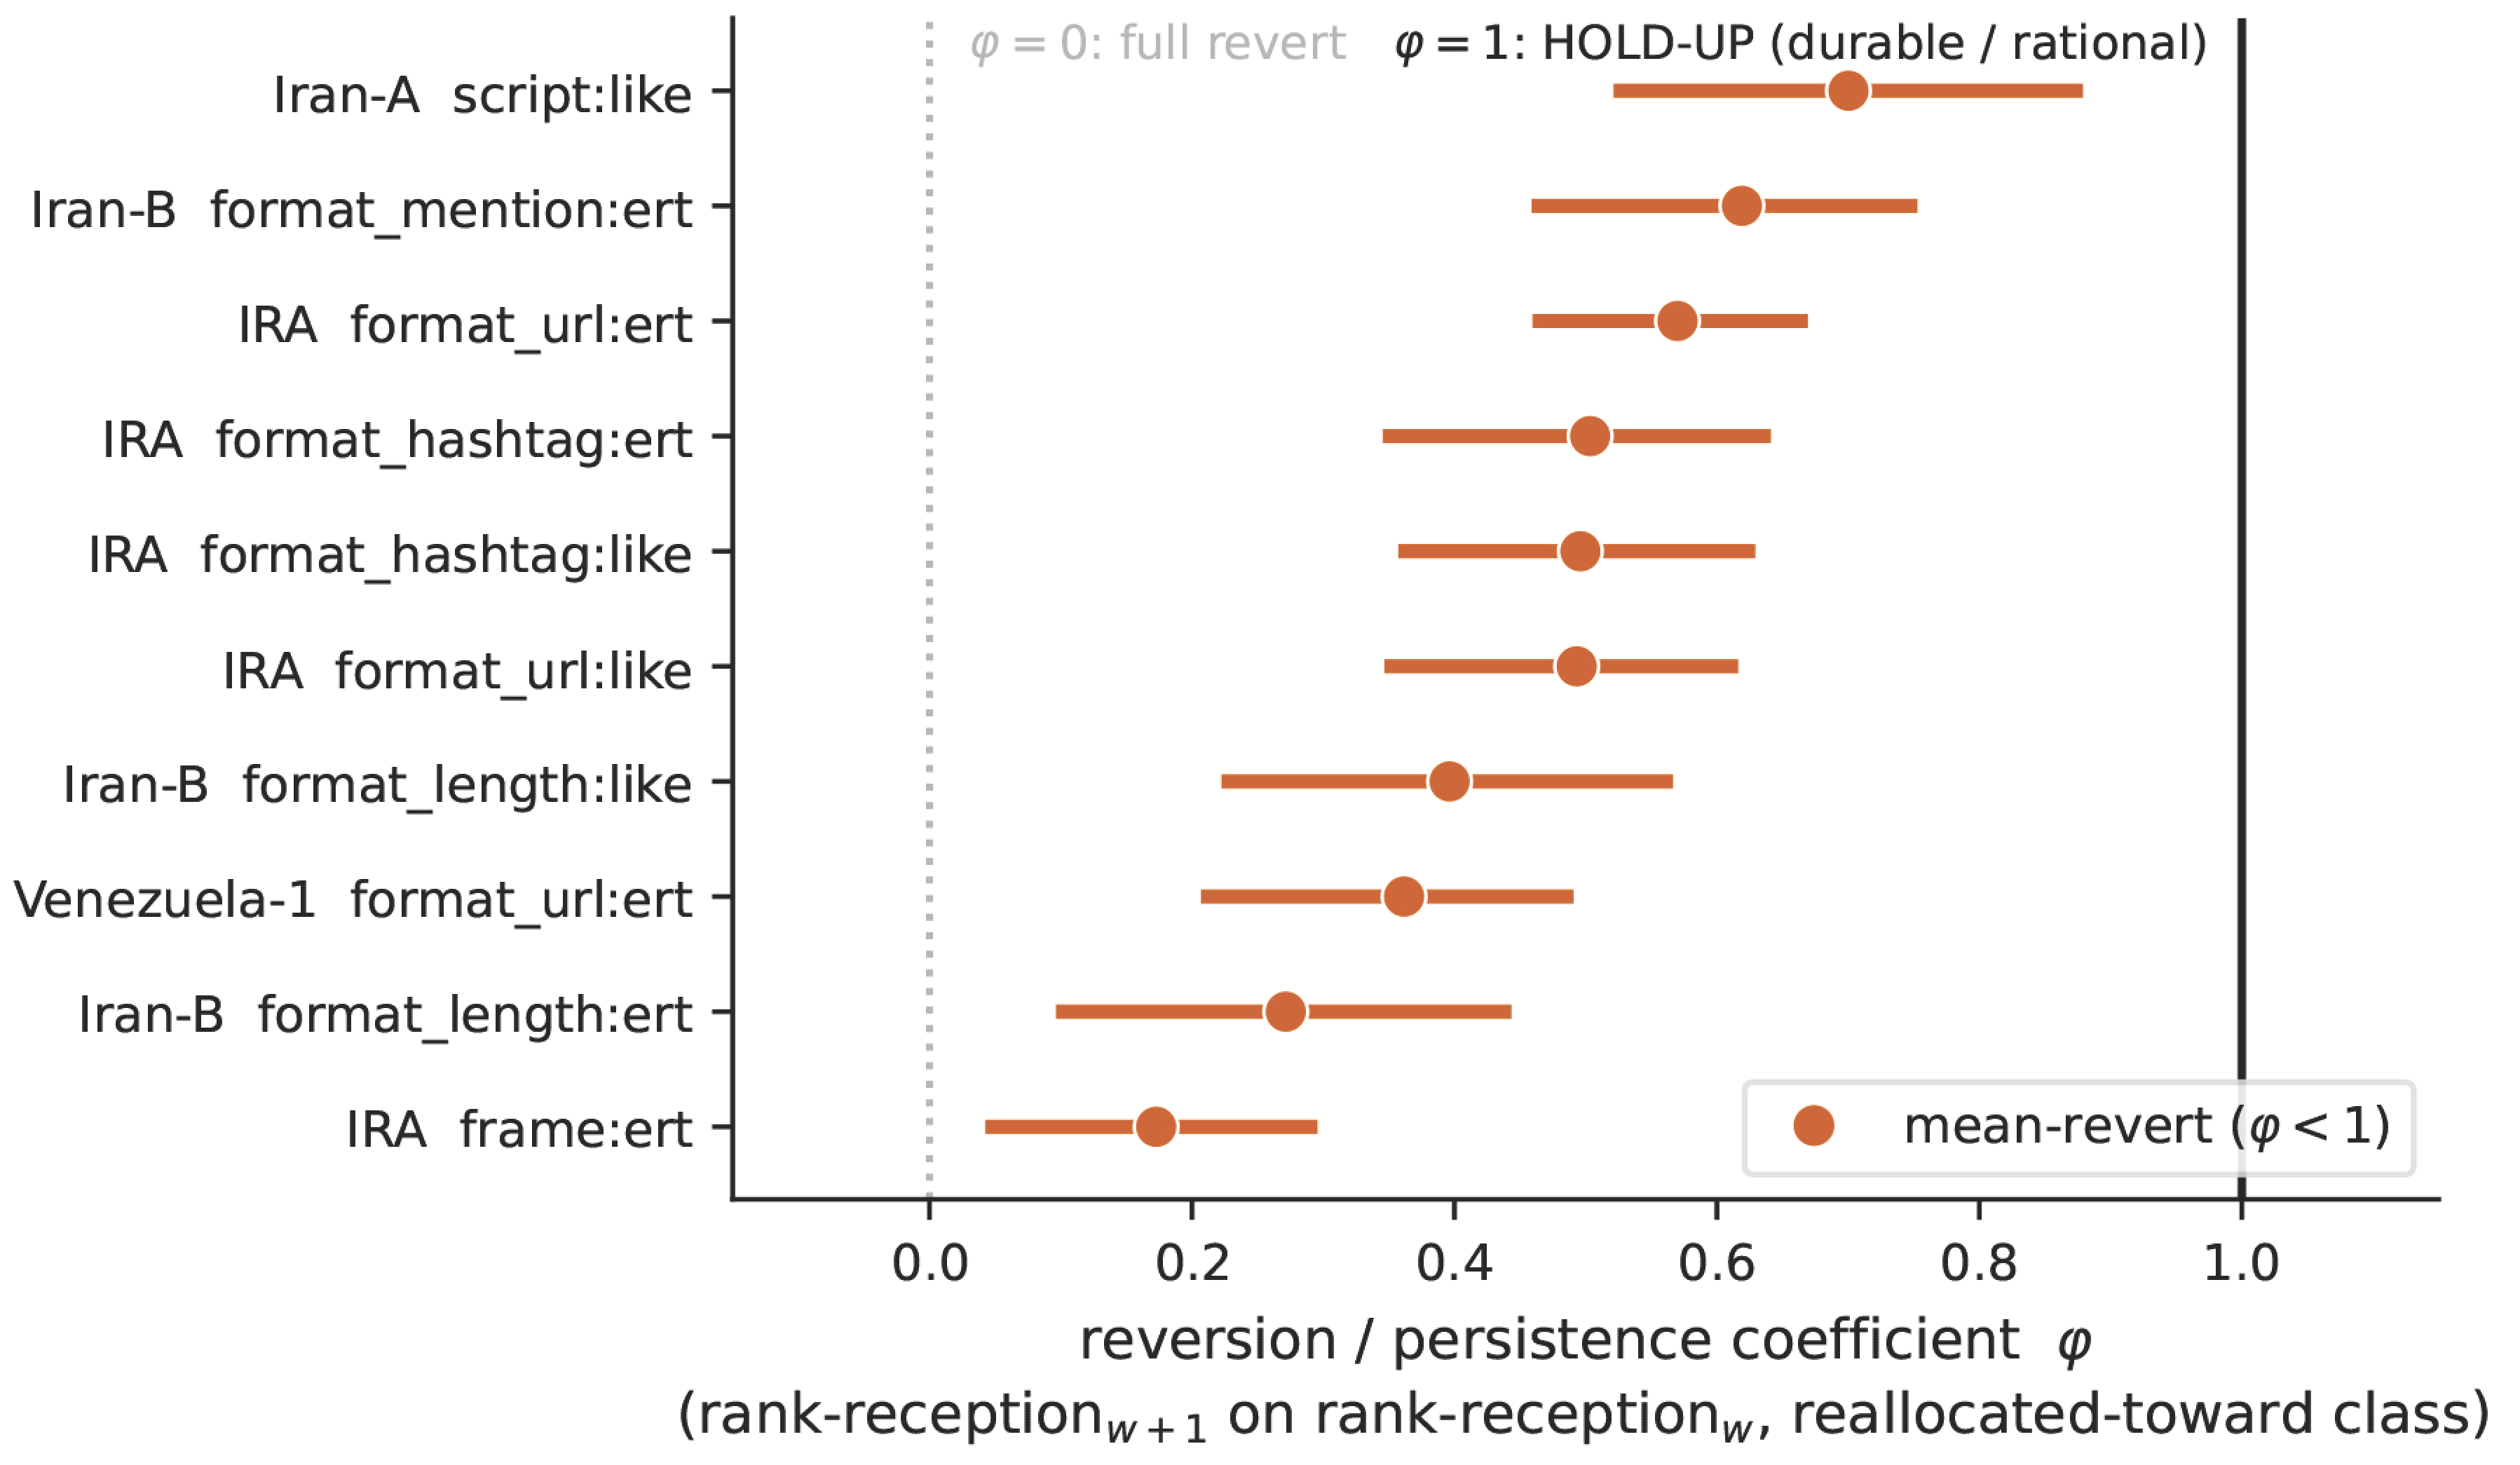
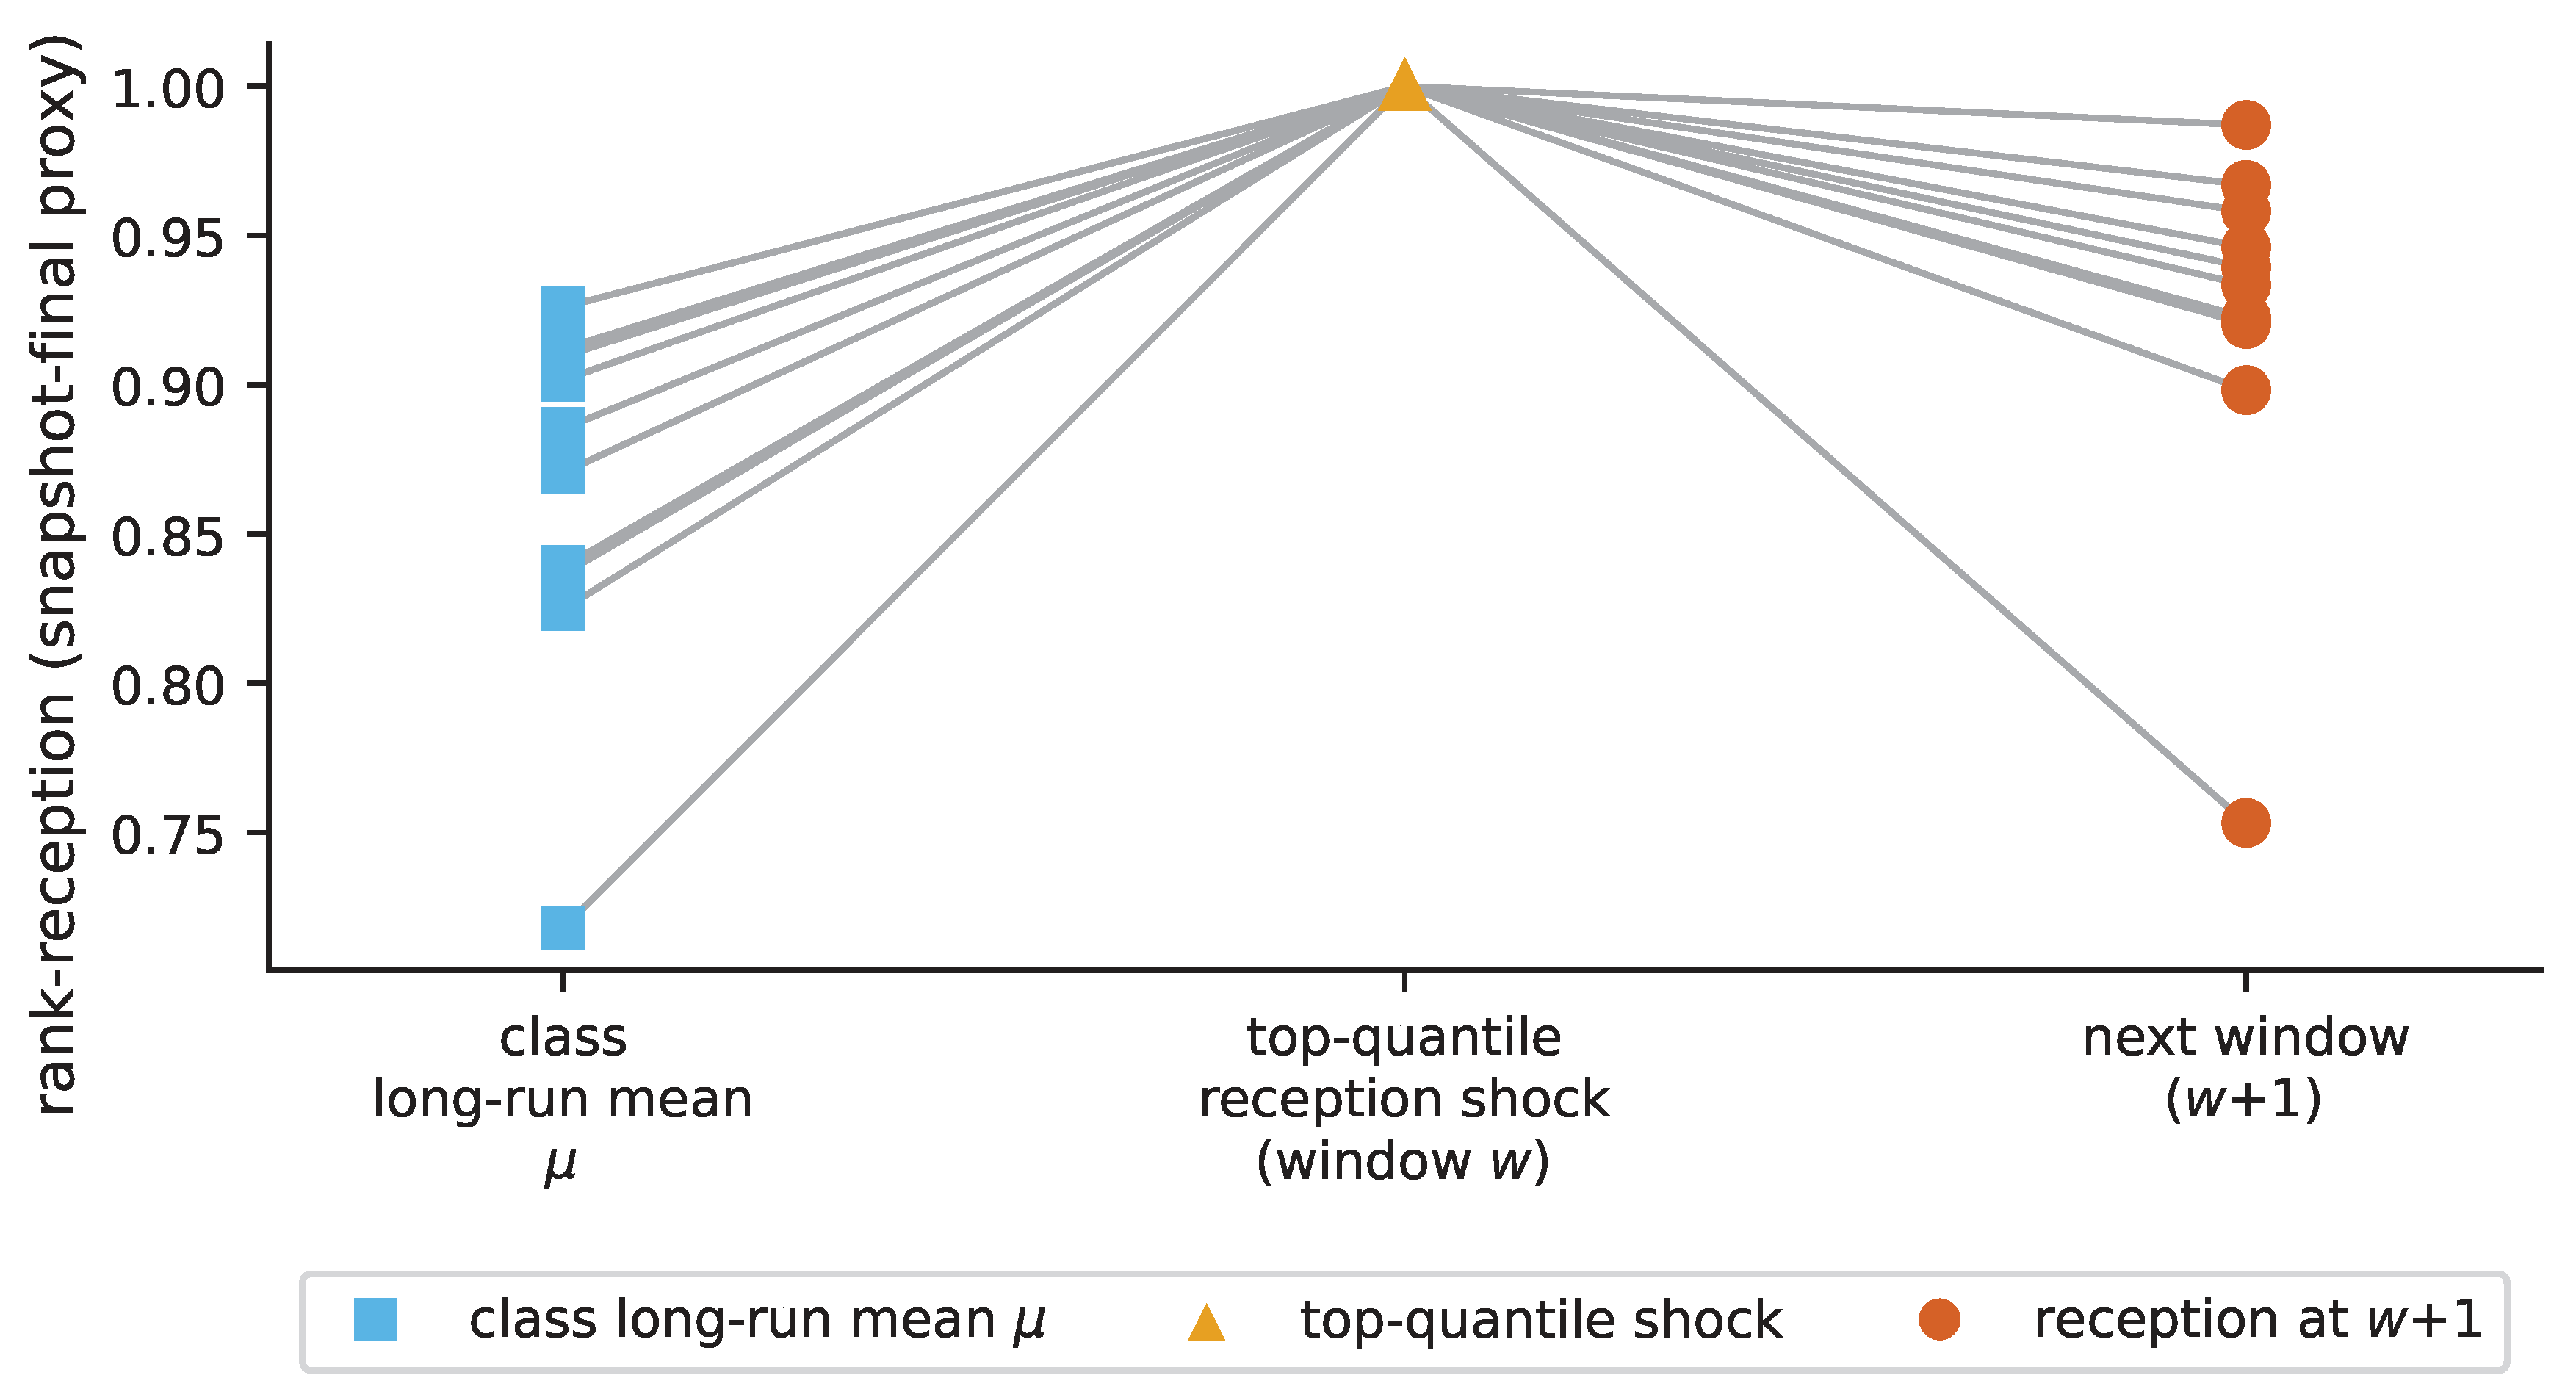
next-window reception, estimated in the same specification, is smaller than half the matched past coefficient in absolute value. Cells failing (i) are scripted; cells failing (ii) are absorbed by trend and autocorrelation; cells failing (iii) are trend artifacts, an apparent adaptation that is time-symmetric and therefore cannot be feedback. For the cells that survive, we ask whether reception-chasing yielded a durable benefit, regressing the favored class’s next-window reception rank on its current rank (a Galton mean-reversion regression, with a 2000-iteration moving-block bootstrap): a slope near 1 would indicate a durable hold-up of the gained reception; a slope below 1 indicates the gain decays.
Appendix B states every term.
The operations are scripted, not feedback-adaptive (
Figure 7 and
Figure 8). Of 110 feasible operation-level cells, only 9 (
) are genuinely feedback-consistent once the placebo is applied; 18 (
) are the corpus’s
largest apparent-adaptation coefficients, unmasked by the placebo as time-symmetric trend; and 83 (
) are flat. Eight of the nine surviving cells are surface-presentation axes (whether to include a URL, hashtag, or mention), never content; the cleanest case, the share of IRA originals containing a URL, shows the canonical signature (past-reception coefficient
, placebo coefficient slightly negative). And every feedback-consistent cell
mean-reverts: Galton coefficients of
–
with every bootstrap interval strictly below 1, a median
of each reception shock reverting within one window, and transient responses to noise rather than durable optimization, with no durable retention of the reception gain. The IRA shows content drift
negatively associated with its own reception gradient: it moves away from, not toward, the agendas that earned the most engagement. Feedback, where present, is centralized at the operation or desk level and essentially absent at the account level (the feedback-consistent count collapses
from operation to desk to account). Without the placebo, the 9 genuine cells and the 18 trend artifacts together would have read as some 27 “learning” cells.
These operations are
playbook-executed, not feedback-adaptive. We use “learn” descriptively, never as a claim of cognition or operator intent, and all relationships are associational. Scripted is not the same as harmless, and it sets a baseline: an adversary that genuinely optimized against reception, as large language models now make feasible [
38,
66], would look measurably different from this. That contrast is a forward warning, not a present finding.
8. Myth 5: “Indistinguishable from Real Users” (And Its Mirror, “Still a Crude 2016 Troll”)
Two opposing folk beliefs coexist, both widely circulated in news and policy reporting (
Appendix A). One holds that modern IO accounts are individually indistinguishable from real users: the human-operated troll accounts in coordinated networks “present traits more similar to regular users” and lack the synchronization signatures of bots, so that loose coordination, not individual features, is what detection must target [
41]; our own clustering work similarly finds trolls “appear indistinguishable” on behavior and intermingle with genuine accounts [
29,
40]. The other holds that operations remain catchable by 2016-era linguistic fingerprints: behavioral and linguistic signatures separate trolls from users at high accuracy [
42], content-based features generalize across campaigns and platforms [
44], and dozens of deception-linked language markers achieve strong classification [
43]. Recent detectors bear out both halves of this tension: cross-campaign linguistic drift forces continual model adaptation [
45,
46], while fused coordination signatures remain the durable tell [
48,
49]. We test both against the matched organic baseline.
On the five campaigns with a matched control arm, we re-compute the 49-cue deception fingerprint and a battery of coordination-network detectors in the family established for uncovering coordinated activity [
47] (same-minute synchrony, copypasta text similarity, co-retweet synchrony, co-hashtag) for IO versus matched real users. Each detector has a fixed operational definition, frozen across both arms with no re-tuning: same-minute synchrony counts one-minute buckets in which two accounts are co-active; copypasta similarity clusters near-duplicate originals at a character five-gram Jaccard similarity of at least
(minimum 25 characters and 4 tokens); co-retweet synchrony links accounts that retweet the same tweet within one minute, at a floor of ten distinct co-retweeted tweets; and co-hashtag activity links accounts by hashtag co-use with analogous floors.
Appendix B tabulates every threshold, and
Appendix C reports the sensitivity of the contrasts to the detector windows, similarity tiers, and control-draw counts. Because the baseline draws are budget-limited (ten matched draws give a one-sided
p-floor of
), a contrast is declared abnormal only when the
confidence interval excludes 1
and the ratio exceeds 1.
The language has evolved off the 2016 fingerprint, but the coordination has not (
Figure 9). The deception fingerprint only partially replicates (mean sign-agreement
across the confirmed five, ranging
–
): the “non-immediate, low-affective stance” markers persist, but the conversational markers the 2016 literature relied on (questions, punctuation, hashtags)
reverse, with IO using fewer in every campaign. Modern IO in this corpus is more moralized and more negatively emotional than organic users while being
less conversational, the opposite of the 2016 high-hashtag, high-engagement conversational profile. Nevertheless, on coordination, the operations are abnormal relative to matched real users: same-minute synchrony runs
–
organic, copypasta similarity
–
, and co-retweet synchrony
–
in the powered campaigns, while co-hashtag, as pre-registered, realizes the predicted negative-control null (
–
, never above 1) in every campaign, confirming that the matched baseline did not manufacture the contrasts.
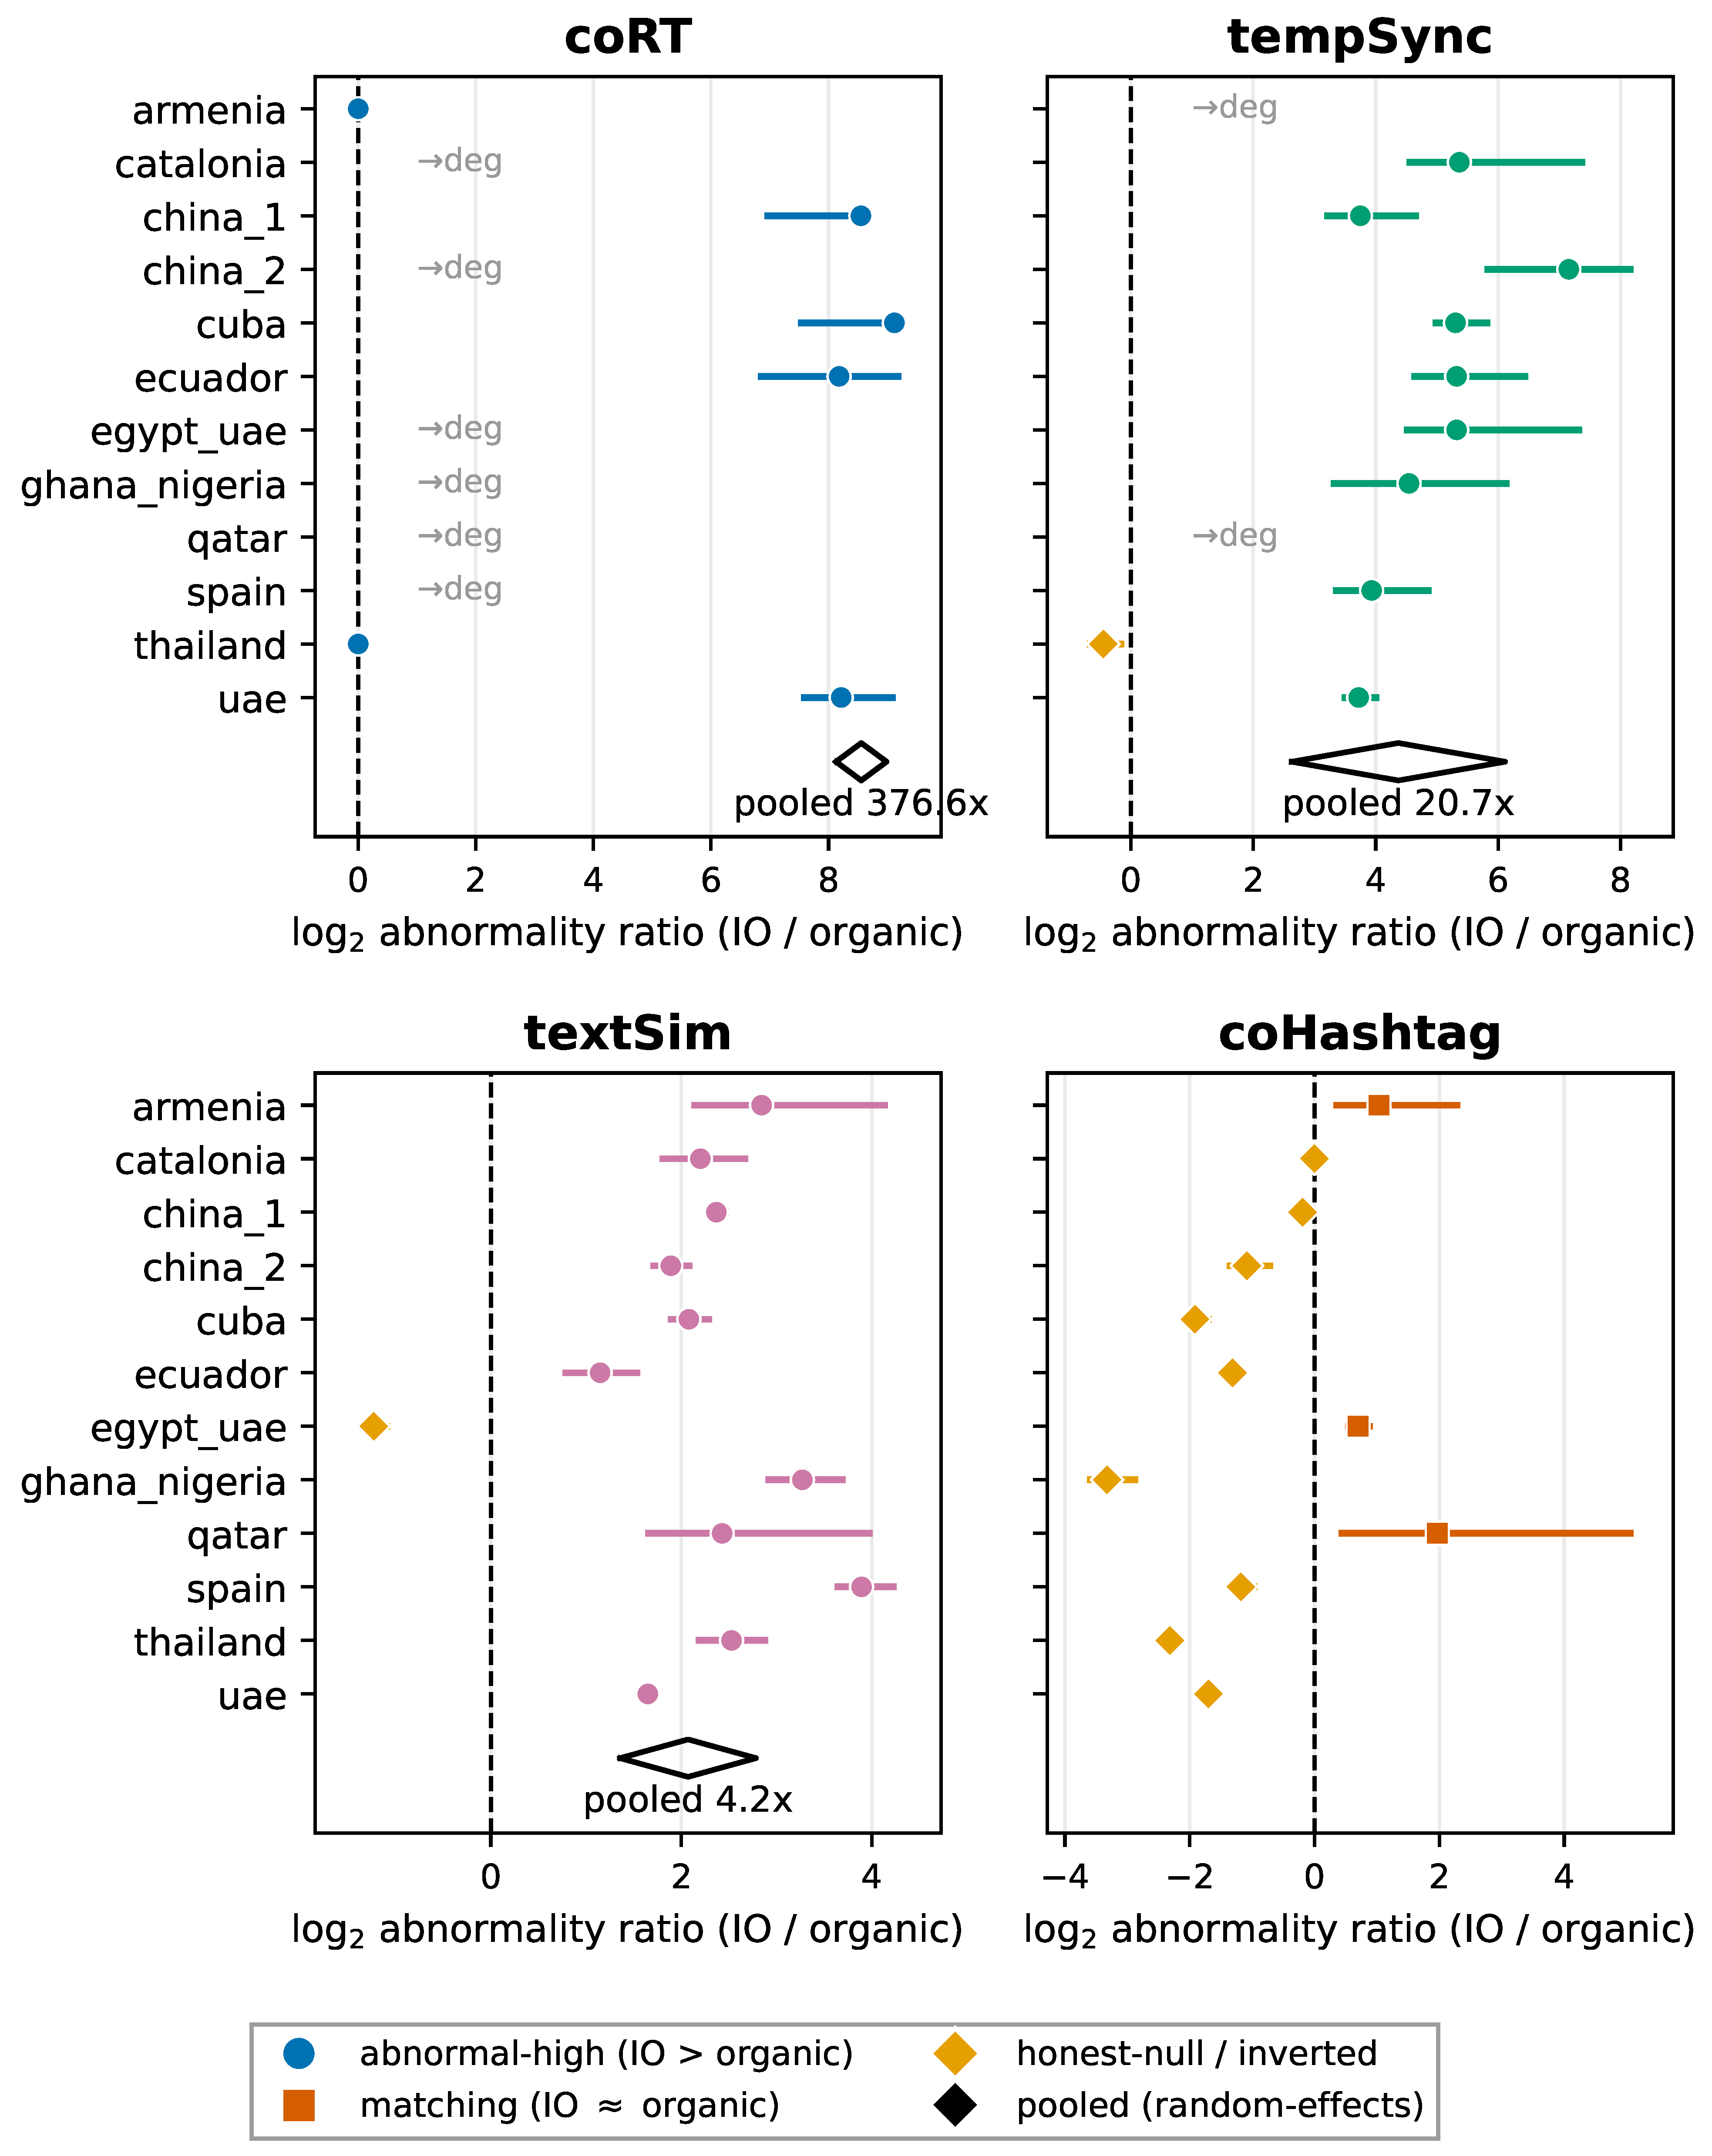
To test whether these are regularities or artifacts of the original four countries, we re-ran the frozen pipeline (no re-tuning) on twelve
new, non-corpus country-groups against their matched controls (
Figure 10,
Table 5). All three regularities replicate out-of-sample, and the null of indistinguishability is rejected in every country: copypasta similarity is abnormally high in 11 of 12 (pooled random-effects ratio
, CI
), same-minute synchrony in 11 of 12 (
,
), co-retweet synchrony in 10 of 12 (
where finite), and the co-hashtag negative-control null reproduces in 9 of 12. The language-drift split reproduces (mean English sign-agreement
), and cross-campaign content segregation persists (
below null,
), indicating no global template. Four small-arm country-groups (Armenia 31, Qatar 29, Ghana 60, Catalonia 76 IO accounts) lean on degeneracy-driven verdicts, and three co-hashtag matches fail on the smallest arms; we flag these rather than down-weighting them.
Neither folk belief holds: these operations no longer talk like 2016 trolls, but they still coordinate like machines. The detectable signature has migrated from language to coordination, and that migration is cross-national.
9. Discussion
Before interpretation, the findings should be separated by epistemic grade because they are not all of one kind. Some are
directly observed in the archives: the segregation lifts, the reach-decomposition shares, and the detector statistics on the operations’ own accounts. Some are
inferred from matched comparisons and inherit the matching’s assumptions: the staffing contrast against organic crowds and the coordination abnormality ratios against matched organic users. And some are
only partly identified: the composition of the external audience behind captured reach (organic uptake versus undetected coordination, not computable in takedown data) and the Myth 2 verdict, which rests on a placebo anchor rather than a like-for-like organic comparison. The paragraphs below keep these grades distinct, and
Table 3 records them claim by claim.
The five corrected findings are not five disconnected negatives; they compose a single, coherent account. These operations are industrial content factories: compartmentalized into nationally fingerprinted desks (Myth 1), thinly staffed by few operators executing calendars rather than crowds of improvisers (Myth 1), producing content on a script rather than optimizing it against reception (Myth 4). What they cannot do internally is make that content travel: the moral-emotional lever that the folk model treats as their primary mechanism does not move reception in their own data (Myth 2), and their viral reach is predominantly captured from an external audience they do not control rather than manufactured by their own retweets (Myth 3). What durably distinguishes them from real users is not the content of any single account, whose language has converged toward the ordinary (Myth 5), but the machine-like coordination across accounts that persists regardless of individual-account linguistic convergence (Myth 5). “Siloed in production, coordinated in execution” is not a contradiction; it is the corrected mechanism.
The hardest limit in this paper, that we cannot decompose external reach into organic uptake and undetected coordination (Myth 3), is partly backstopped by the coordination evidence (Myth 5). The two myths use the word “synchrony” for two different objects, and separating them is what makes the reconciliation work. Under Myth 5, the discriminating signal is cross-account same-minute synchrony: many accounts acting in lockstep, which is what separates the operations from matched organic users at 7–. Under Myth 3, the question is whether within-author seeding synchrony, one account’s own co-timed posting of a viral original, predicts how far that original then travels externally; it does not, and, in the IRA and Iran, it weakly anti-predicts reach. These are consistent: cross-account coordination is a reliable indicator of inauthenticity, but the same synchrony does not drive external reach. Thus, where reach is observable, on the operations’ own accounts, the synchrony that marks the operation as coordinated is precisely not the mechanism that propagates its content externally; the diffuse external sharing that does carry the bulk of reach shows no such lockstep signature in the operations where we can look. The unresolved part of the reach question, whether the external pool is organic or partly undetected coordination, is therefore bounded by what coordination looks like where we can measure it: if undetected coordination were carrying the external reach, it would have to do so without the same-minute, copypasta, and co-retweet signatures that coordination otherwise leaves in every measurable context. This is an inference from the internal accounts to an unobservable external pool, not a measurement of that pool; it narrows the question rather than closing it.
The common thread across all five myths is that a corpus of platform-confirmed manipulation will, analyzed without a baseline, a placebo, or false-discovery control, reproduce the patterns analysts expect to find. A meaningless count of the letters x, y, and z predicts engagement on these samples (Myth 2); the corpus’s largest “adaptation” coefficients are time-symmetric trend (Myth 4); within-corpus significance on the manipulation arm says nothing about how these accounts compare to real users until an organic arm is added (Myths 2 and 5). Pre-registration, matched baselines, placebo features, and permutation nulls are not procedural formalities here; they are what separates a genuine regularity from a spurious artifact. Several of our positive controls (detectors that do fire on coordination, a co-hashtag negative control that reproduces as a clean null, a fingerprint classifier that separates campaigns at high accuracy) demonstrate that the null findings are not attributable merely to insufficient statistical power.