


Abstract
Cross-lingual voice cloning must preserve the reference voice while following the requested language or dialect. We diagnose reference-side interference in dots.tts across Amdo, U-Tsang, and Kham Tibetan; Mandarin; and English. Across the tested conditions, control gains were statistically inconclusive or accompanied by losses in speaker similarity and intelligibility. The primary 147-row display matrix was deduplicated into 120 unique reference–target conditions with five fixed reference prompts. A three-model speaker-disjoint waveform evaluator (SDWE) achieved language-level accuracy of 0.978 and a macro-averaged F1 score (macro-F1) of 0.976; its Tibetan-subset macro-F1 of 0.644 makes dialect findings exploratory. Within this matrix, disabling prompt latent prefill in the baseline system reduced language-level leakage from 0.262 to 0.095, while the crossed-cluster 95% confidence interval, , included zero. Reference x-vector re-pairing showed no stable benefit over a budget-matched continuation; fixed-ratio gating missed the joint control and fidelity criteria; and strong classifier guidance reduced speaker similarity to 0.602 without improving target-dialect hits. A separate prespecified development stress test used 30 tasks, ten distinct reference recordings—two per variety, nine outside the primary matrix—and six target texts. None of nine block-by-time prompt-path masks qualified, and every crossed-cluster confidence interval included zero. An independent Hidden-Unit BERT (HuBERT) layer-9 audit on a source-group-disjoint cohort obtained a dialect macro-F1 of and retained strong source information, so it serves as sensitivity evidence rather than replacing the primary evaluator. A 20-task evaluation by one native Tibetan listener remains exploratory case-level evidence. The combined results identify English-reference-to-Tibetan synthesis as the most concentrated failure route and show that fixed global or block-time interventions do not provide stable target control across the tested prompts and texts.
1. Introduction
Zero-shot voice cloning transfers speaker characteristics from a reference utterance to new target text, reducing the adaptation cost for new speakers and low-resource languages. In cross-lingual and cross-dialect settings, a reference utterance also encodes language, dialect, accent, prosody, and local pronunciation habits. When the reference variety conflicts with the target text, these attributes may be transferred to the output, reducing intelligibility in the target language, overriding the requested dialect, or leaving a perceptible source-side accent.
The three major Tibetan dialect groups considered here, Amdo, U-Tsang, and Kham, provide a useful setting in which to study this conflict. They exhibit fine-grained dialectal differences while coexisting with Mandarin Chinese and English in a single low-resource multilingual model. Matched-variety synthesis and reference-conflict synthesis test distinct capabilities: producing the requested variety and maintaining that control when the reference carries competing linguistic information.
We distinguish three levels of evidence: category leakage in generated speech, dialect information decodable from a speaker representation, and the response to an intervention on a conditioning path. Reference-side category leakage denotes an output classified as the reference language or dialect when the target requests a different category. The language-level objective accent leakage rate (), operationalized as the reference-language assignment rate, and the objective dialect leakage rate () measure this discrete event. A representation probe measures dialect decodability, while generation interventions test how changing a conditioning path affects the output. Native-listener judgments provide a separate perspective on accent, speaker identity, and clarity.
The central aim is to diagnose conditioning-path behavior and determine the operating limits of interventions for reference-side leakage. The main comparisons provide no consistent evidence of improved target control: most paired confidence intervals include zero, and stronger interventions incur fidelity costs. These results organize the study around pathway diagnosis, matched controls, and evaluation validity.
Our study uses dots.tts and a frozen 147-row reference–target display matrix covering Amdo, U-Tsang, Kham, Mandarin, and English, with one fixed reference prompt per variety. Deduplication by reference prompt, target variety, and target text yields 120 unique analytical conditions. We denote the adapted model before reference re-pairing as Base. We first compare its complete reference-cloning path, denoted as Full, which uses both a speaker x-vector and prompt latent prefill, with an x-vector-only path. This ablation tests whether local prompt context and the global speaker representation contribute differently to reference-side leakage. We then assess reference x-vector re-pairing () during training, followed by prompt gating and classifier-guided decoding () during inference. Main-matrix generated speech is scored with a frozen speaker-disjoint waveform evaluator (), implemented as a three-model probability ensemble. Target-variety accuracy, source-category leakage, speaker-embedding cosine similarity (), and automatic speech recognition (ASR) error rates are reported separately.
Two targeted audits extend the evidence around the main matrix. A prespecified development prompt-path stress test uses ten distinct reference recordings (two per variety), six new target texts, and 30 balanced tasks; nine of the recordings are outside the main matrix. It tests nine fixed diffusion-transformer (DiT) block-by-flow-time masks under a frozen decision rule. An independent self-supervised representation audit compares features from Hidden-Unit BERT (HuBERT) and Cross-Lingual Speech Representation (XLS-R) on natural speech with source-group-disjoint Tibetan partitions. Because prompt identifiers do not establish speaker identity, the stress test treats reference recordings as prompt clusters rather than independent speakers. The two audits test reference-condition sensitivity and evaluator dependence without changing the main matrix endpoints.
The study addresses four questions:
- Does cross-lingual leakage propagate primarily through prompt latent prefill or through the speaker x-vector, and does cross-dialect leakage follow the same pathway?
- Does reference x-vector re-pairing increase the priority of target-side control when the full prompt is retained?
- Is there a stable operating point or prompt-path region that improves target control without sacrificing speaker similarity or intelligibility, including across an expanded set of reference recordings and target texts?
- How robust are the dialect findings to an independent self-supervised representation, and do under-represented dialects, particularly Kham, exhibit distinct control and intelligibility failures?
The contributions of this work are as follows:
- We establish a diagnostic protocol that separates target-category control, reference-category leakage, speaker similarity, and intelligibility. The , a source-group-disjoint audit using HuBERT and XLS-R representations, and paired listening define the evidence available for language-level and exploratory dialect analysis.
- We characterize conditioning-path differences through Full versus x-vector-only generation, a speaker-metadata-group-disjoint x-vector probe, and a 30-task prompt-path stress test with ten reference recordings. The main matrix locates the largest language-level leakage cluster in English-reference-to-Tibetan synthesis, while the expanded stress test measures sensitivity across prompt and text clusters.
- We evaluate training-time reference re-pairing and inference-time interventions through a budget-matched continuation, fixed-ratio prompt gating, controlled ablations, and block-by-time prompt-path masks. Their control and fidelity profiles establish tested operating limits and identify concrete targets for subsequent model development.
2. Related Work
2.1. Low-Resource and Cross-Lingual Speech Synthesis
Low-resource speech synthesis commonly transfers knowledge from high-resource languages through speaker adaptation, cross-lingual state mapping, or multilingual neural architectures. Prior Mandarin–Tibetan studies showed that Mandarin corpora can improve Tibetan synthesis while retaining some bilingual capability [1,2,3,4,5]. End-to-end text-to-speech (TTS) and zero-shot voice-cloning systems have subsequently incorporated reference waveforms, discrete tokens, and continuous acoustic latents into the generation process [6,7,8,9,10,11]. These advances improve flexibility but also introduce more routes through which language-specific information in the reference can affect the output.
2.2. Multi-Dialect Tibetan Synthesis
Explicit control of Amdo, U-Tsang, and Kham has been supported by multi-dialect datasets and modeling work. Tibetan dialect corpora, the few-shot multi-speaker multi-dialect TTS system FMSD-TTS, and the Tibetan multi-dialect TTS framework TMD-TTS address parallel data, few-shot multi-speaker modeling, and unified dialect conditioning, respectively [12,13,14]. Recent work has also explored adapting large pretrained models to low-resource Tibetan synthesis [15]. Most of these studies evaluate the forward mapping from a target dialect label to the intended dialect. We examine the complementary failure mode: whether a conflicting reference condition pulls the output back toward the source dialect or language.
2.3. Speaker Transformation and Reference-Side Leakage
Voice conversion studies how acoustic transformations convey a target speaker’s identity while preserving linguistic content. Al-Radhi et al. integrate a continuous vocoder with a feed-forward deep neural network to map continuous fundamental frequency, maximum voiced frequency, and spectral features between speakers, and evaluate speaker similarity and naturalness separately [16]. This distinction between identity transfer and output quality also informs reference-conditioned voice cloning: speaker similarity, intelligibility, and target-language or target-dialect control each require a dedicated measure. Our evaluation examines their joint behavior when reference and target varieties conflict.
In reference-conditioned synthesis, speaker embeddings, prompt prefill, and local acoustic context can encode language, dialect, prosody, and content alongside speaker identity. AccentBox quantified speaker–accent entanglement and accent hallucination [17]. CrossAccent-TTS, language-agnostic speaker embeddings, CrossSpeech, and mixture-of-language-experts models have addressed speaker–language or speaker–accent coupling through representation disentanglement, acoustic-path separation, and expert routing [18,19,20,21]. Large cross-lingual systems such as Qwen3-TTS and CosyVoice 3 also report accent drift as a distinct evaluation dimension [22,23]. We operationalize reference-side category leakage for Tibetan dialect identity and audit its pathways in the continuous flow-matching conditioning stack of dots.tts. This connects output-level category errors with representation probes and interventions on individual conditioning paths.
2.4. Guided Generation and Representation Disentanglement
Plug-and-Play Language Models (PPLM), Guided-TTS, Universal Guidance, FreeDoM, and diffusion posterior sampling demonstrate that pretrained discriminators can guide generation without retraining the base generator [24,25,26,27,28]. Our implementation adapts this guidance framework to flow-matching velocity parameterization. It defines a contrastive target-minus-source objective on a closed-form clean-latent estimate and constrains each update with proximal restoration and trust-region clipping. Domain-adversarial learning and the variational information bottleneck provide related motivations for suppressing domain information in speaker representations [29,30]. Together, these approaches motivate testing training-time x-vector re-pairing and inference-time guidance as interventions on distinct conditioning pathways, with target control and acoustic fidelity evaluated jointly.
3. Problem Formulation and Methods
3.1. Task Definition
Let denote the source variety of a reference utterance and the variety requested by the target text. The five varieties are Amdo Tibetan (bo-amdo), U-Tsang Tibetan (bo-utsang), Kham Tibetan (bo-kham), standard Mandarin Chinese (zh-standard), and standard English (en-standard). Given reference speech r and target text , the system generates the output in Equation (1):
An intended output should preserve the speaker timbre in r, render the text intelligibly, conform to , and avoid transferring irrelevant source-language, source-dialect, or prosodic attributes.
For a cross-lingual set and a Tibetan cross-dialect set , the categorical leakage rates are defined in Equations (2) and (3):
where and are the language-collapsed and five-class decision functions of the frozen , respectively. Lower values indicate that fewer outputs are assigned to the reference category. These metrics quantify discrete category assignment; the listening task examines perceived leakage, timbre, and clarity.
3.2. Base Model and Conditioning Paths
dots.tts processes Tibetan Unicode text and uses three target-dialect tokens: <|dialect_amdo|>, <|dialect_utsang|>, and <|dialect_kham|>. We denote the adapted checkpoint before reference x-vector re-pairing as Base. The global speaker condition is produced by the dots.tts SpeakerXVectorFeatures module, which wraps the 3D-Speaker context-aware masking (CAM++) encoder, implemented by the CAMPPlus class [31]. The speaker branch resamples the prompt to 16 kHz, computes an 80-bin Kaldi filterbank with a 25 ms window, 10 ms hop, zero dither, and per-bin temporal mean normalization, and returns a 512-dimensional embedding. Generation multiplies this embedding by the fixed speaker scale of 1.5 before global conditioning. The five trimmed prompts last 5.47–9.89 s, below the extractor’s 10 s crop limit. Checkpoint and preprocessing details are given in Appendix B.
The complete reference-cloning condition, denoted as Full, uses both the speaker x-vector and prompt latent prefill. Its generation schedule places the target-dialect token before the prompt transcript and inserts the variational-autoencoder (VAE) prompt-latent patches into the acoustic history. Prompt prefill introduces local reference context into generation and can carry source language, dialect, and prosody. The x-vector-only condition sets use_prompt_prefill=false: it removes the prompt transcript and prompt-latent span from the generation schedule, attaches the target-dialect token to the target text, and retains the global speaker condition. The retained x-vector includes any variety information encoded in the global speaker representation.
For a gated prompt scale s, the Full sequence structure and prompt transcript remain present. At each prompt position, the acoustic patch embedding is mixed with the non-acoustic base embedding at ratio s, and the prompt latent inserted into the flow-matching history is multiplied by s. We evaluate at inference. Consequently, x-vector-only is a categorical path ablation rather than the member of this gated sequence: it changes both the sequence structure and the acoustic prefill path.
Figure 1 summarizes the diagnostic design. Path ablation locates candidate conflict pathways, budget-matched continuation tests the contribution of , and prompt gating and characterize inference-time control and fidelity trade-offs.
Figure 1.
Experimental design and evidence chain. (a) Reference speech and target text with a variety-control token. (b) Speaker x-vector, prompt latent prefill, and target-text conditioning paths. (c) Full versus x-vector-only path ablation, versus budget-matched Base training, and prompt-gating/ inference interventions. (d) The frozen evaluator, speaker similarity, intelligibility, and exploratory native-listener evaluation support claims of different strengths.
3.3. Expanded-Reference Prompt-Path Stress-Test Design
To test the prompt pathway beyond the five-reference matrix, we prespecified and froze a separate development set of 30 tasks at the step-1400 checkpoint (@1400). The set contains ten distinct reference recordings, two for each of the five varieties, and six target texts, two for each Tibetan target dialect. Nine reference recordings are outside the main matrix. Candidate target texts were selected by stable hashing after excluding every main-matrix target text and every prompt transcript. The task set contains 12 cross-language conflicts, 12 cross-dialect conflicts, and six same-variety safety conditions. Recording identifiers are used as prompt-cluster labels; the available metadata do not establish ten independent speaker identities.
The intervention removes only attention edges from the current four-frame latent query to prompt-latent keys. The x-vector, target text, prompt transcript, classifier-free guidance, initial noise, generated history, and numerical solver remain fixed. The 18 DiT blocks are partitioned into early (0–5), middle (6–11), and late (12–17) groups, and the ten Euler steps into early (0–2), middle (3–6), and late (7–9) windows. Their Cartesian product defines nine fixed block-by-time masks. Baseline generation and all nine masks each cover the same 30 tasks, yielding 300 formal outputs. Three additional no-op generations install an empty mask and test implementation identity against the corresponding baselines.
For each conflict task, the frozen used by this stress test provides the margin in Equation (4):
and the paired intervention effect is . The primary statistic is the median over the 24 conflict tasks. Section 4.2 specifies the frozen decision rule and cluster bootstrap.
3.4. Reference X-Vector Re-Pairing
During training, the target sample’s text, language/dialect control token, and acoustic latent remain unchanged, while its reference x-vector is replaced by that of sample j. When i and j belong to different varieties, the model must derive target pronunciation from the text-side condition while retaining speaker information from the reference side. This intervention is intended to strengthen conditional role separation while retaining the reference x-vector’s full representation.
We evaluate -Full and -x-vector-only together with Base-Full and Base-x-vector-only in an initial checkpoint comparison. Of 995,000 training rows, 149,062 (14.98%) were assigned cross-speaker, cross-variety x-vectors using pairing seed 48. To isolate training-budget confounding, we also trained a matched Base continuation from the same step-3000 Base checkpoint (Base@3000) using the unmodified Base manifest. The matched Base and continuations share training seed 47, learning rate, validation set, and a 2000-step budget. Checkpoints were evaluated every 100 updates. The selection score is the unweighted mean of the Amdo, U-Tsang, Kham, Mandarin, and English validation losses, where each loss combines the flow-matching and end-of-sequence (EOS) terms; lower is better. reaches its minimum score at step 1400, and matched Base is evaluated at the same update count. The test matrix, , , ASR, and listener results did not enter checkpoint selection. Full validation histories and training settings are provided in Appendix B.
3.5. Classifier-Guided Decoding
For the flow-matching parameterization , the clean latent estimate from current latent z and predicted velocity is given by Equation (5):
The control model is a five-class latent-space classifier for Amdo, U-Tsang, Kham, Mandarin, and English. It applies two 1D convolutional layers (128→256, kernel size 5) with Gaussian error linear unit (GELU) activations, concatenates temporal mean and standard deviation, and uses a 512→256→5 multilayer perceptron (MLP), for approximately 0.5 million parameters. Training uses balanced subsets of 60,000 utterances and 4000 validation utterances, with random 4–32-frame latent crops. Utterance identifiers do not overlap across the split; 2455 of 2460 validation speaker identifiers also occur in training. The selected model obtains 0.980 full-sequence accuracy and 0.776 single-four-frame-patch accuracy. Selection uses the latter because queries one current clean-latent patch. This classifier supplies a differentiable control signal and is not used as an independent outcome evaluator; Appendix B gives the training and validation record.
Given target variety and reference variety , the contrastive guidance objective is defined in Equation (6):
Guidance is applied within using the trapezoidal window in Equation (7):
Thus for and is zero outside the guidance window. With , the root-mean-square (RMS) normalized displacement before proximal restoration is defined in Equation (8):
If denotes the unmodified anchor, proximal restoration is given by Equation (9):
We fix the guidance step size at , reference-penalty weight at , and proximal-restoration weight at , and scan . The radius bounds the pre-restoration displacement ; the applied displacement is . At , an target-only control and an equal-norm random-direction control are also evaluated. The scan characterizes the control and fidelity response to increasing strength.
4. Experimental Setup and Evaluation Protocol
4.1. Route-Balanced Evaluation Matrix
The frozen display matrix contains 147 reference–target rows spanning Tibetan cross-dialect, cross-lingual, and matched-variety controls. Each of the five varieties contributes one fixed reference prompt, yielding five reference recordings in total. Because the same reference prompt, target variety, and target text can occur in more than one matrix file, rows are deduplicated before analysis using stable reference-prompt identity, reference and target variety, and target-text identifier. This procedure produces 120 unique conditions. The resulting denominators are 36 for , 42 for , 75 for target-variety accuracy, and 120 for . Target-variety accuracy excludes code-mixed text, for which no single target-language label applies. Each metric uses its corresponding eligible subset of the 120 unique conditions. Table 1 details the matrix composition.
Table 1.
Frozen objective evaluation matrix. The 147 display rows are deduplicated by stable condition keys into 120 unique conditions. All systems use the same reference–target pairs, random seed, and decoding configuration.
The initial checkpoint comparison comprises Base-Full, Base-x-vector-only, -Full, and -x-vector-only. The primary training attribution compares matched Base@1400 with @1400. Both continue from the same Base@3000 checkpoint with identical training budgets, seeds, validation settings, and decoding configurations. Their manifests are independently deduplicated and evaluated on 120 shared keys. The main scan and controls also use all 120 unique conditions, including 36 cross-dialect and 42 cross-language conditions for the corresponding leakage metrics. The nine-condition set is the focused English-reference-to-Tibetan prompt-gating experiment, rather than the main evaluation. The separate prompt-path stress test uses 30 tasks with ten reference recordings and six new target texts, as described in Section 3.3. To reduce listening burden, ordinary same-language and same-dialect text and code-mixed text are excluded from the subjective comparison, and one target text is retained per reference–target variety pair in the listening set.
4.2. Objective Metrics and Statistical Analysis
The was trained only on labeled natural speech; generated speech was never used for training. An audit of an earlier evaluator revealed extensive speaker overlap among training, validation, and test partitions. Its accuracy and macro-averaged F1 score (macro-F1) of 0.9775 and 0.9776 are therefore excluded from the final evidence chain. The revised speaker-disjoint manifests used to train the contain 69,424 training, 9125 validation, and 9008 test utterances. Speaker overlap and aggregate-speaker rows are zero. Seven data sources remain shared across partitions, so evaluation measures transfer across speakers within a shared source pool.
Three component classifiers were trained with random seeds 20260821, 20260822, and 20260823 using class-weighted loss. Each checkpoint was selected only by validation macro-F1, with validation loss as a tie-breaker. The averages class probabilities across the three models; no model was selected using the test set. As shown in Table 2, five-class test accuracy and macro-F1 are 0.837 and 0.774, respectively. After collapsing Tibetan dialects, language-level accuracy and macro-F1 are 0.978 and 0.976. Within the Tibetan subset, macro-F1 is 0.644 and Kham F1 is 0.330. Accordingly, supports the language-category analysis and supports exploratory dialect analysis. These validation scores describe category discrimination on natural speech; their relationship with generated-speech perception is discussed in Section 6.4.
Table 2.
Performance of the three-model ensemble on the speaker-disjoint test set. Language-level scores collapse the three Tibetan dialects into Tibetan. Tibetan-subset macro-F1 is recomputed on the 5008 Tibetan test utterances; the per-class F1 values below use the full five-class test set.
We also conducted an independent self-supervised representation audit to determine whether a second feature family strengthens Tibetan dialect evaluation. Frozen HuBERT [32] layers 6, 9, and 12 and XLS-R [33] layers 6, 12, 18, and 24 were mean–standard-deviation pooled at the utterance level. The complete audit contains 5671 unique natural-speech recordings; its Tibetan cohort contains 1849 utterances partitioned into 24/9/9 train/development/held-out source groups with zero source overlap. For each of three random seeds (1201, 1202, and 1203), standardized features feed a balanced logistic regression classifier; the dialect probe uses source-group-equal sample weights. Candidate selection uses only train/development data and the frozen score , where is matched-text content concordance and is normalized source invariance. HuBERT layer 9 ranks first on development data. On held-out source groups it obtains dialect accuracy of and macro-F1 of ; an auxiliary source-decoding classifier obtains macro-F1 of against the nine-class uniform baseline 0.111. Values are means ± standard deviations across the three seeds. Table 3 contrasts the roles of the two audits. The cohorts and split units differ, so the scores are sensitivity evidence rather than a pooled or formal head-to-head comparison. The independent audit does not establish a source-robust replacement for the prespecified synthesized-speech evaluator and is not used to rescore synthesized speech.
Table 3.
Primary waveform evaluator and independent self-supervised representation audit. The cohorts, labels, and split units differ, so the numerical scores are not a direct model comparison. HuBERT values are means ± standard deviations across three seeds. The HuBERT result tests sensitivity to feature architecture and source-group separation; it is not used to rescore synthesized speech.
In addition to O-ALR and O-DLR, we report target-variety accuracy, speaker-embedding cosine similarity (), Mandarin character error rate (CER), English word error rate (WER), and Tibetan CER. Mandarin and English use Whisper large-v3 from openai-whisper==20231117. Decoding forces the requested language (zh or en), uses temperature 0 and half-precision inference on a graphics processing unit (GPU), and otherwise retains the package defaults. Mandarin scoring removes whitespace, ASCII punctuation, and common Chinese punctuation before character-level CER. English scoring converts to lowercase; retains a–z, digits, and apostrophe; maps other characters to spaces; collapses whitespace; and computes word-level WER.
Tibetan is recognized with an internally developed, proprietary, unpublished Zipformer-based ASR model deployed through sherpa-onnx. This model was reported to achieve 87–93% comprehensive recognition accuracy across the three Tibetan dialects. Separately, an Amdo Zipformer trained on 535.9 h of speech reported a WER of 14.14%. Both figures are pre-export results. The deployed recognizer uses Open Neural Network Exchange (ONNX) files identified internally as epoch-30-avg-1; conversion to ONNX may introduce a small accuracy loss, but the post-conversion difference has not been independently quantified. Audio is converted to mono, 16 kHz, signed 16-bit waveform format. The recognizer uses an 80-bin filterbank, zero dither, and greedy-search decoding without a language model, hotwords, or blank penalty. Tibetan normalization removes whitespace, shad-family sentence delimiters, and ASCII punctuation while retaining the tsheg; CER is computed over the remaining characters. All three languages use jiwer==4.0.0. ASR scoring covers monolingual Tibetan, Mandarin, and English samples; code-mixed samples are excluded. Appendix B identifies the inference files and records the complete decoding configuration.
For the focused prompt-gating scan, four operational expansion criteria were fixed before generation and scoring: at least 6/9 target-language assignments, a positive mean target-minus-reference probability margin, mean , and mean Tibetan CER . The hit count requires target control in at least two thirds of the route cases, and zero is the direct decision boundary for the probability margin. The floor lies between the already frozen Full and x-vector-only route endpoints, while the CER ceiling matches the weaker of the two x-vector-only endpoint means to two decimals. These criteria screen whether to expand a setting to the full matrix; they are not hypothesis-test thresholds. We also compare each intermediate setting directly with both endpoints, so the conclusion does not depend on a single cutoff.
For the expanded-reference prompt-path stress test, the 95% interval for median is estimated by independently resampling reference-prompt and target-text clusters 10,000 times. A block-by-time cell qualifies only if its conflict-task median is at least 0.20 with a confidence-interval lower bound above zero, its cross-language and cross-dialect medians are both positive, at least two of three target-dialect medians are positive, its language-collapse increase is at most 0.05, and its median same-variety target-probability decrease is at most 0.05. These criteria and the nine cells were frozen before generation. A qualifying cell would advance to a separate confirmation set; if no cell qualifies, the fixed-mask experiment stops at the stress-test stage.
Two-sided exact McNemar tests describe paired categorical outcomes at the condition level. The primary uncertainty interval for each paired difference is a crossed-cluster paired bootstrap that independently resamples reference prompts and target-text identifiers. When an earlier Base manifest lacks reference_prompt_name, prompt identity is recovered from the portable filename in reference_wav, preserving each reference prompt as a separate cluster. We use 10,000 bootstrap replicates and report 95% intervals. The total matrix contains five prompt clusters and the cross-dialect subset three. These cluster counts limit precision along the reference-prompt axis; repeating target texts adds conditions within the same reference clusters. The resolution of O-DLR, O-ALR, and target accuracy is , , and , respectively. Point estimates and paired intervals are interpreted together: intervals containing zero leave the direction of the difference unresolved at the stated confidence level.
4.3. Exploratory Native-Listener Evaluation
The listening interface presents anonymized paired Base-Full and -Full outputs. Each task contains a reference X and anonymous outputs A and B. The listener evaluates target language/dialect control and reference-side leakage, speaker-timbre similarity to X, and naturalness and clarity. “Tie” and “cannot judge” responses are permitted. Optional issue labels include reference-side leakage, incorrect target, content or pronunciation error, noise, distortion, and timbre mismatch. The task is a paired comparison with an explicit reference.
The frozen set contains 20 tasks: 14 cross-lingual and six cross-dialect comparisons. One native Tibetan listener completed all tasks. The responses form an exploratory case-level error analysis, with the listener as the single source of perceptual judgments. A broader evaluation should determine sample size from a minimum meaningful effect and prospective power analysis, balance listener dialect backgrounds and familiarity, and account for repeated judgments by each listener. Appendix C records the responses and specifies the proposed design and agreement analysis.
5. Results
5.1. Language-Level Pathway Diagnosis and Exploratory Dialect Results
The reveals a comparatively large cross-lingual path difference within the frozen conditions. Within the 42-condition cross-language subset, Base O-ALR decreases from 0.262 under Full conditioning to 0.095 under x-vector-only conditioning. For the Full-minus-x-vector-only contrast, the crossed-cluster 95% confidence interval is . Across 75 eligible conditions, target-variety accuracy increases from 0.493 to 0.600 when prefill is disabled; expressed as Full minus x-vector-only, its interval is . , evaluated over all 120 unique conditions, changes from 0.850 to 0.856, with an interval of . Across the 36-condition cross-dialect subset, O-DLR remains 0.222 in both modes, with an interval of (Table 4). These estimates identify prompt latent prefill as a candidate cross-lingual conflict pathway in the fixed-reference matrix. The paired intervals include zero, leaving the magnitude and direction of the effect across reference prompts uncertain.
Table 4.
Full-minus-x-vector-only pathway differences and reference-prompt × target-text crossed-cluster paired bootstrap 95% confidence intervals. Differences are computed before rounding. A positive difference means that Full has a higher value. Positive values are unfavorable for leakage and favorable for target accuracy and . There are five reference prompts overall and three in the O-DLR subset.
Route-level counts show that this effect is heterogeneous. English-reference-to-Tibetan synthesis forms the most concentrated language-category leakage cluster for Base-Full, and this cluster contracts when prefill is disabled (Figure 2). Tibetan-reference-to-Mandarin routes do not show the same consistent direction. The route breakdown identifies the reference–target combinations that contribute to the aggregate O-ALR difference. Figure 3 summarizes the paired pathway effects across both checkpoints.
Figure 2.
Cross-lingual reference-category leakage by route for the Base system. (a) Full reference path. (b) X-vector-only path. Each valid cell reports the number of outputs classified as the reference language divided by the route denominator. Color normalization from 0 to 1 is shared across panels; gray dashes denote within-language routes or routes excluded from cross-lingual analysis. English-reference-to-Tibetan synthesis is the most concentrated Full-condition failure cluster, but other routes do not change uniformly.
Figure 3.
Paired Full versus x-vector-only pathway effects. (a) Leakage metrics are expressed as Full minus x-vector-only, so positive values indicate more leakage with prefill. (b) Target accuracy and are expressed as x-vector-only minus Full, so positive values favor prefill removal. Filled circles/solid lines denote Base; open squares/orange lines denote . Error bars are crossed-cluster 95% bootstrap intervals from 10,000 independent resamples of reference prompts and target-text identifiers. Intervals containing zero indicate uncertainty in the direction of the paired difference. Tibetan dialect results are exploratory.
The x-vector analysis provides complementary evidence. A linear classifier predicts Tibetan dialect from x-vectors extracted from natural speech with 0.672 accuracy under a speaker-metadata-group-disjoint split, compared with a majority baseline of approximately 0.530 and a uniform-random baseline of 0.333. Accuracy under a random utterance split reaches 0.844, consistent with a contribution from speaker overlap (Table 5; Figure 4). Kham has 25 speaker-metadata groups, and a small number of groups represent aggregate or unknown identities. The grouped result estimates dialect decodability with residual identity, source, and recording-channel variation. Section 6.2 explains how these factors affect the representation analysis.
Table 5.
Linear probing of dialect from x-vectors. The uniform-random baseline is 0.333 and the test-set majority baseline is approximately 0.530. The primary split separates available speaker-metadata groups; residual aggregate/unknown identities and shared source/channel factors are described in Section 6.2.
Figure 4.
Frozen t-distributed stochastic neighbor embedding (t-SNE) projection of speaker x-vectors extracted from natural Tibetan speech. Color and marker jointly identify Amdo (), U-Tsang (), and Kham (). The exploratory projection describes the joint variation of dialect, speaker, recording channel, and collection batch. The quantitative grouped probe is reported in Table 5.
The independent self-supervised representation audit gives a second view of dialect-evaluator dependence (Table 3). On its source-group-disjoint natural-speech cohort, HuBERT layer 9 reaches dialect accuracy and macro-F1 , while source macro-F1 remains . The and this audit use different cohorts and split units, so their scores do not form a paired model comparison. The audit does not establish a source-robust alternative for rescoring synthesized speech or class-level evidence for improved Kham discrimination; the remains the prespecified synthesized-speech outcome evaluator.
5.2. RXP Under Budget-Matched Training
The initial checkpoint comparison is summarized in Table 6. Relative to Base-Full, -Full changes O-ALR from 0.262 to 0.214, O-DLR from 0.222 to 0.194, target accuracy from 0.493 to 0.560, and from 0.850 to 0.846. For Base minus , the crossed-cluster intervals for O-ALR and O-DLR are and , respectively; the target-accuracy interval is . All three intervals cross zero. Because the checkpoints differ in training budget, the comparison combines continuation-training and re-pairing effects; the matched continuation separates these factors.
Table 6.
Base/× Full/x-vector-only results under the . Values are computed from 120 unique conditions. The denominators for O-DLR, O-ALR, target accuracy, and are 36, 42, 75, and 120. Downward and upward arrows indicate that lower and higher values are preferred, respectively.
The budget-matched comparison addresses this confound. Matched Base and continue from the same Base@3000 checkpoint with the same seed, learning rate, validation set, and 2000-step budget. They are paired on 120 shared unique conditions at step 1400 (Table 7; Figure 5). Under Full conditioning, matched Base and yield O-ALR values of 0.190 and 0.214 and target accuracies of 0.547 and 0.560; both difference intervals cross zero. Their O-DLR values are 0.278 and 0.194, and the Base-minus- interval has a lower bound of zero. This dialect-level contrast is exploratory: its evaluator has a Tibetan-subset macro-F1 of 0.644 and the subset contains three reference-prompt clusters. Under x-vector-only conditioning, intervals for O-ALR, O-DLR, and target accuracy also cross zero. The contrast favors matched Base by 0.020 (95% interval ). The matched comparisons provide no consistent evidence of a target-control improvement from within this evaluation matrix.
Table 7.
Paired comparison of the budget-matched Base continuation and @1400 under the . Both continue from Base@3000 with a 2000-step budget. Results use 120 shared deduplicated keys. Differences are Base minus and are computed before rounding; intervals are reference-prompt × target-text crossed-cluster paired bootstrap 95% confidence intervals.
Figure 5.
Paired effects of matched Base@1400 versus @1400. Every contrast is oriented so that positive values favor : leakage uses Base minus , whereas target accuracy and use minus Base. Filled circles denote Full and open squares denote x-vector-only. Error bars are crossed-cluster 95% bootstrap intervals. Most intervals cross zero; the x-vector-only interval lies entirely below zero and favors matched Base.
The paired ASR comparisons quantify intelligibility alongside control (Table 8). Under Full conditioning, Tibetan CER is 0.092 for matched Base and 0.099 for , Mandarin CER is 0.074 and 0.030, and English WER is 0.041 and 0.024. All three paired intervals cross zero. Under x-vector-only conditioning, Tibetan CER is 0.085 and 0.071, with an interval that also crosses zero; Mandarin CER is identical, and the absolute English WER difference is 0.006. The paired ASR results leave the overall intelligibility difference unresolved.
Table 8.
ASR intelligibility comparison between matched Base and @1400 on shared test keys. Tibetan uses the internally developed Zipformer-based recognizer; Mandarin and English use Whisper large-v3. Differences are Base minus and are computed before rounding, with crossed-cluster paired bootstrap 95% confidence intervals. Code-mixed text is excluded.
Aggregate comparisons obscure route-specific failures. Under scoring, English-reference-to-Tibetan leakage occurs in 6/9 Base-Full outputs (O-ALR = 0.667) and 5/9 -Full outputs (0.556), compared with 1/9 and 2/9 for their x-vector-only counterparts. The path-ablation point-estimate change is larger than the Base-versus- difference on these nine conditions, directing attention to the prompt pathway for this reference–target route.
5.3. Fixed-Ratio Prompt Gating: Control and Fidelity
We tested whether simple prompt attenuation could repair the concentrated English-reference-to-Tibetan conflict. Prompt-prefill scales of 0.1, 0.2, 0.4, and 0.7 were evaluated on nine English-reference-to-Tibetan conditions for both checkpoints (Table 9; Figure 6). All eight intermediate settings fell outside the joint acceptance region. At scale 0.2, both Base and achieved 6/9 Tibetan-language hits, but fell to 0.761 and 0.749 and Tibetan CER was 0.175 and 0.207, respectively. At scale 0.1, every output from both checkpoints was classified as English. The conclusion is also threshold-independent: for both checkpoints, no intermediate scale simultaneously matches the Full endpoint’s and the x-vector-only endpoint’s target-hit count and CER.
Table 9.
Targeted English-reference-to-Tibetan scan on nine tasks under the . The operational screen, fixed before generation and scoring, requires at least 6/9 Tibetan target hits, a positive control margin, , and Tibetan CER . X-vector-only is a categorical path ablation, not gated scale 0. Downward arrows indicate that lower values are preferred.
Figure 6.
Fixed-ratio prefill gating for English-reference-to-Tibetan synthesis. (a) Target-language hits among nine tasks for Base and . X-vector-only is displayed as a separate categorical ablation; 0.1–1.0 are gated prompt-path scales, with 1.0 denoting Full. The dashed line marks the minimum 6/9 hit criterion. (b,c) Tibetan CER– trajectories. The green region requires CER and ; filled markers have a positive target-versus-reference control margin. No intermediate scale matches both endpoint objectives.
The x-vector-only endpoint is a structurally different ablation, not gated scale 0. It removes the prompt transcript and all prompt-latent positions, whereas scale 0.1 retains the Full prompt sequence and target-token placement while inserting the acoustic prompt at 0.1 amplitude. The apparent 8/9-to-0/9 Base transition therefore crosses both sequence structure and acoustic magnitude. Neither checkpoint was trained with fractional prefill, and the changed early context propagates through the subsequent generation trajectory. This implementation accounts for the discontinuity between the two named conditions; it does not define a continuous dose response between them.
5.4. Expanded-Reference Prompt-Path Stress Test
The separate prespecified development stress test expands reference coverage to ten distinct recordings, two per variety, and six target texts; nine of the recordings are outside the main matrix. Baseline generation and the nine block-by-time masks completed 30/30 tasks each, for 300 formal outputs. The three empty-mask no-op waveforms were bit-identical to their paired baselines, confirming that installing the intervention hook alone did not change generation.
No fixed mask produced a stable target-over-reference margin improvement (Figure 7). All nine crossed-cluster confidence intervals include zero, and 0/9 cells satisfy the frozen decision rule. The largest median change occurs for the early-block/early-step mask (, 95% interval ), but its U-Tsang-target median is . The middle-block/late-step mask has median (95% interval ), while its cross-dialect median is . These sign reversals across target dialects and conflict types prevent both cells from qualifying. The task-level changes establish that direct prompt-latent attention affects the output, whereas the cluster results show that one globally fixed block/time mask does not provide stable control across the tested prompt and text clusters. Under the frozen protocol, no cell advanced to confirmation.
Figure 7.
Prespecified development prompt-path stress test on 24 conflict tasks within the 30-task set. (a) Median paired change in target-minus-reference log-probability margin for each DiT-block group and Euler-step window. Positive values favor the requested target. (b) Median changes with reference-prompt × target-text crossed-cluster 95% bootstrap intervals from 10,000 replicates. The dashed line marks the prespecified minimum effect of 0.20; every interval crosses zero, and 0/9 cells qualify. In panel (b), blue circles and intervals denote non-negative median changes, whereas orange squares and intervals denote negative median changes.
5.5. CGD: Fidelity Costs and Exploratory Dialect Control
The shows unchanged or higher exploratory dialect-leakage estimates under (Table 10). The no-guidance O-DLR is 0.194, remains 0.194 at and 6, and rises to 0.222 at and 20. Strong guidance reduces O-ALR to 0.048 but does not improve overall target accuracy; it also reduces to 0.602 and raises Tibetan CER to 0.207. The reduction in reference-language assignment is accompanied by a substantial fidelity cost.
Table 10.
trust-region scan on @1400 under the . Radius clips the RMS-normalized displacement before proximal restoration. All systems are evaluated on the same 120-condition matrix; the denominators for O-DLR, O-ALR, target accuracy, and are 36, 42, 75, and 120, respectively. O-DLR is an exploratory dialect proxy. Downward and upward arrows indicate that lower and higher values are preferred, respectively.
Output destinations reinforce this conclusion (Table 11). At , 0.36 of the 36 unique cross-dialect outputs are classified as the target dialect, 0.22 as the reference dialect, and 0.25 as non-Tibetan. The corresponding no-guidance proportions are 0.36, 0.19, and 0.31. These assignments replace scores from the excluded speaker-overlapping evaluator documented in Appendix A. Figure 8 shows extensive overlap among O-DLR intervals and a marked reduction at .
Table 11.
Exploratory category assignments for 36 unique Tibetan cross-dialect outputs from @1400 and its variants under the . O-DLR treats every category other than the reference dialect as non-leakage, so target-dialect, other-Tibetan, and non-Tibetan assignments are reported separately. Shares may not sum to one because of rounding.
Figure 8.
Exploratory cross-dialect control and fidelity under . (a) O-DLR– point estimates with reference-prompt × target-text crossed-cluster 95% bootstrap intervals under the . Lines indicate the scan order and do not imply continuous interpolation. (b) Destinations of 36 unique cross-dialect outputs: target dialect, reference dialect, another Tibetan dialect, or a non-Tibetan category. O-DLR intervals overlap extensively; the main change at is a pronounced loss of with unchanged target-dialect hit rate.
Table 12 provides the corresponding destination breakdown for O-ALR. The target, reference, and other shares are mutually exclusive and sum to one across the 42 cross-language conditions. For Base@3000, disabling prefill changes the distribution from 30/11/1 to 36/4/2. At , reduces reference-language assignments from 9 to 2 relative to its @1400 Full baseline, while other-language assignments increase from 0 to 7 and target-language assignments remain 33. Thus, the lower O-ALR at this setting reflects both reduced reference assignment and increased diversion to an unintended third language.
Table 12.
Language destinations for the 42 unique cross-language conditions under the . Each entry reports count (share). Target and reference denote the languages requested by the target text and supplied by the reference prompt, respectively; other denotes the remaining language. O-ALR is the reference-language share. The baseline is @1400 Full.
Controlled ablations at separate the effects of guidance direction and the source penalty (Table 13). The equal-norm random direction leaves O-DLR at 0.194; removing the source penalty () changes it to 0.250; and full yields 0.222. Target-dialect hit rates are 0.36 for the baseline, random-direction control, and full , and 0.39 for the target-only control. These exploratory category assignments accompany the control–fidelity trade-off: full lowers O-ALR, reduces , and increases Tibetan CER.
Table 13.
Controlled ablations of strong guidance at on @1400 under the . All systems are evaluated on the same 120-condition matrix; the denominators for O-DLR, O-ALR, target-dialect hit, non-Tibetan rate, and are 36, 42, 36, 36, and 120, respectively. The random direction retains the same norm normalization and trust-region clipping as . Downward and upward arrows indicate that lower and higher values are preferred, respectively.
Automatic intelligibility results are reported in Table 14. Tibetan CER remains close to the no-guidance condition at moderate guidance strengths but approximately doubles at . Kham has the highest CER in every system. With the same Tibetan Zipformer recognizer, median robust CER on held-out natural speech is 0.020 for Amdo, 0.082 for U-Tsang, and 0.035 for Kham. The natural-speech comparison identifies synthesized Kham as a priority for error analysis. Its interpretation depends on the recognizer’s transfer from natural to synthesized speech and on audio–text alignment quality.
Table 14.
Automatic intelligibility under on @1400. Tibetan CER is reported for Amdo/U-Tsang/Kham/all Tibetan. Code-mixed rows are excluded. Tibetan values aggregate 15 unique monolingual conditions per dialect and 45 overall. Downward arrows indicate that lower values are preferred.
5.6. Exploratory Listener Results
In the 20 anonymized paired tasks completed by one native Tibetan listener, was preferred in six cases, Base in seven, and seven were tied for target control/reference leakage. For naturalness and clarity, was preferred in five cases, Base in seven, and eight were tied. All 20 speaker-timbre comparisons were tied. The English-reference-to-Amdo, Kham, and U-Tsang tasks were all annotated as showing similarly clear leakage in both systems; the Kham and U-Tsang cases were specifically described as having a severe English accent. These case-level descriptions align with the objective route-level failure cluster and identify the perceived accent errors associated with it.
6. Discussion
6.1. Synthesis Capability and Reference-Side Leakage Are Distinct
Content accuracy, speaker preservation, and target-variety control describe complementary aspects of cross-lingual voice cloning. Matched-language and matched-dialect controls establish synthesis capability, while CER and WER measure the preservation of the requested content. Reference-side interference can alter the output language or introduce a reference-associated accent in otherwise intelligible speech. Joint evaluation with O-ALR, exploratory O-DLR, target-category assignments, and exposes these differences and distinguishes content-generation errors from reference–target conflicts.
6.2. Interpretation of the Conditioning-Path Evidence
The path ablation identifies prompt latent prefill as a candidate pathway for language-level interference. On the Base checkpoint and five fixed reference prompts, disabling prefill reduces the O-ALR point estimate and increases target-variety accuracy, while the O-DLR point estimate remains unchanged. The crossed-cluster confidence intervals include zero, leaving the direction and magnitude of effects across independent reference prompts unresolved. The route breakdown in Figure 2 localizes the observed changes within the tested matrix.
The x-vector probe identifies dialect-associated information in the global speaker representation, with several possible contributors. Speaker identity and dialect are correlated in the available corpus; the higher accuracy under a random utterance split is consistent with the classifier using speaker-specific cues. Separating metadata speaker groups reduces that opportunity, while aggregate or unknown identities leave uncertainty about the independence of the underlying speakers. Recording source, microphone or channel characteristics, and collection batch can also covary with dialect labels and provide predictive cues across speaker groups. Class imbalance further affects raw accuracy, motivating the majority baseline and macro-F1 reported in Table 5. The probe and t-SNE projection therefore describe the joint structure of dialect, identity, and recording conditions. Isolating a speaker-independent dialect component requires verified identities and evaluation across independent sources, channels, and collection batches.
The intervention comparisons distinguish changes in reference conditioning from changes in training budget and generation fidelity. changes the reference x-vector in 14.98% of training rows while retaining the full 512-dimensional representation and the original pairing in the remaining rows. The budget-matched comparison shows no consistent target-control benefit from and favors matched Base in x-vector-only . The intervention therefore does not remove variety-associated coordinates from the global condition or consistently shift the generator toward its target token. This result connects the limited re-pairing rate and retained representation to the absence of stable role separation.
Fixed-ratio gating acts on every prompt patch with one global scalar. The route response is non-monotonic: a scale of 0.1 preserves high while producing English assignments throughout, whereas a scale of 0.2 recovers 6/9 target-language hits at a substantial fidelity cost. A single amplitude cannot select which time positions or acoustic dimensions carry voice identity and which carry source-language context. The categorical x-vector-only ablation also removes the prompt transcript and its sequence positions, explaining why its result is discontinuous from the gated path rather than the endpoint of a smooth scale curve.
The expanded-reference stress test localizes this instability more directly. Masking current-latent access to prompt-latent keys causes large task-level margin changes, while effects vary in sign across prompt, text, dialect, and conflict-type clusters and every confidence interval crosses zero. The direct prompt-latent route therefore participates in generation, but its useful and harmful effects are distributed differently across inputs. This result explains why one global prompt scale or one fixed attention mask cannot supply stable variety control: both apply the same intervention to conditioning patterns whose functional location varies across tasks.
supplies a local gradient from a classifier whose single-patch validation accuracy is 0.776. The classifier can identify useful in-domain variety cues, but its utterance-disjoint validation set shares 2455 of 2460 speaker identifiers with training. At , guidance lowers reference-language assignment while leaving target-dialect hits unchanged, diverting seven cross-language outputs to a third language, reducing to 0.602, and raising Tibetan CER. The target-only and equal-norm random controls show that a strong latent displacement can change classifier scores without recovering the requested variety. Together, the results support a multi-path account: variety cues enter through prompt sequence context and the global x-vector, scalar attenuation cannot selectively separate them, and strong local correction destabilizes the generator’s learned speech trajectory.
6.3. English-Reference-to-Tibetan Synthesis as a Priority Failure Route
English-reference-to-Tibetan synthesis concentrates the language-category leakage observed under Full conditioning. Across the nine tested conditions, outputs are assigned to English in 6/9 Base-Full cases and 5/9 -Full cases, compared with 1/9 and 2/9 under x-vector-only conditioning. This route contributes prominently to the aggregate path-ablation difference in Figure 3. The exploratory listener record supplies a complementary perceptual description: the English-reference-to-Amdo, -Kham, and -U-Tsang tasks show clear leakage in both systems, with a severe English accent specifically noted for Kham and U-Tsang (Appendix C). The categorical assignments and listening notes converge on this route as a concrete target for intervention.
The gating scan shows why route-specific improvement requires joint control and fidelity criteria. At prefill scale 0.2, both checkpoints reach 6/9 Tibetan-language hits, accompanied by lower and higher Tibetan CER; all tested intermediate settings fall outside the joint acceptance region (Figure 6). Future experiments can test explicit target-side conditioning and staged prompt injection on this route, using multiple English reference speakers and recording conditions to determine which effects persist beyond the fixed prompt. This design directly tests whether target-language control can improve while preserving the reference voice and requested content.
6.4. Measurement Validity
The supports language-level category analysis and exploratory Tibetan dialect analysis. Its natural-speech test macro-F1 is 0.976 after collapsing the labels to Tibetan, Mandarin, and English, compared with 0.644 within Tibetan and 0.330 F1 for Kham. The speaker-disjoint split removes the overlap identified in the audit of the excluded predecessor; data sources and potential recording channels remain shared across partitions. These validation results establish the relative strength of language-level and dialect-level classification under the tested natural-speech distribution.
The independent self-supervised representation audit tests whether a second representation supplies a stronger dialect signal. HuBERT layer 9 was selected from seven HuBERT and XLS-R layer candidates using only train/development data and then evaluated once on held-out source groups. Its held-out dialect macro-F1 is , while the same representation predicts the recording source with macro-F1 . The audit and use different natural-speech cohorts and split units, so their F1 values are not a paired model comparison. The independent audit does not establish a source-robust alternative for rescoring synthesized speech. The remains the prespecified outcome evaluator, and O-DLR remains an exploratory proxy accompanied by destination counts, ASR, and listener evidence.
Perceptual validity additionally depends on how the classifier transfers to synthesized speech. A generated utterance can combine intelligible target-language content, reference-associated pronunciation, and synthesis artifacts, whereas the evaluator learns discrete labels from natural recordings. Its natural-speech F1 consequently measures category discrimination in that domain; the correspondence between its generated-speech assignments and listener judgments of accent strength remains uncalibrated. The English-reference-to-Tibetan listening notes provide case-level agreement on a failure route. The 20-task, single-listener record supports this qualitative comparison, with too few independent judgments to estimate proxy–perception agreement across dialects. Continuous accent strength, prosody, and naturalness require separate perceptual ratings, particularly for exploratory Kham results.
Two aspects of the measurement design affect interpretation of intervention outcomes. First, O-DLR counts non-Tibetan generations as non-reference dialects, so a lower value can accompany an incorrect output language. Reporting target, reference, other-Tibetan, and non-Tibetan destinations alongside intelligibility exposes this failure mode. Second, the latent classifier and waveform evaluator share five-class labels and natural-speech training domains. The latent classifier is an utterance-disjoint but speaker-overlapping control model; the waveform evaluator is trained and tested on speaker-disjoint partitions and remains the outcome measure. Guidance can exploit cues shared by the label space without producing a perceptual improvement. The HuBERT audit adds an independent feature architecture and a source-group-disjoint split; its high source predictability does not establish a stronger outcome measure for synthesized speech. Ratings of the same synthesized utterances from multiple listeners remain the direct test of proxy–perception correspondence. Whisper large-v3 language identification has a floor effect on synthetic Tibetan and supplies insufficient discrimination for that comparison.
6.5. Limitations and Research Priorities
The current evidence defines four priorities for broader validation:
- Reference and text coverage. The primary objective matrix contains one fixed reference prompt per variety: five prompts overall and three in the Tibetan cross-dialect subset. The separate stress test expands to two reference recordings per variety, six new target texts, and 30 tasks, with nine of ten recordings outside the main matrix. Its identifiers do not verify independent speaker identities. A broader endpoint study should vary verified speaker identity, prompt content, and recording condition independently. Strictly paired ASR comparisons currently contain 45 Tibetan, 15 Mandarin, and 15 English samples per mode; broader text coverage and code-mixed evaluation would extend the intelligibility analysis.
- Dialect measurement and representation. The combines three component classifiers and scored 1752 generated utterances. The independent audit using HuBERT and XLS-R representations adds source-group-disjoint testing, but its selected representation reaches macro-F1 and preserves strong source information. External source- and channel-disjoint testing, posterior calibration, and verified speaker metadata would strengthen both the evaluator and the x-vector analysis. Kham warrants additional speakers, texts, and independent recording batches given its low classification F1 and high synthesized-speech CER.
- Perceptual validation. The listening evaluation is exploratory, with one native Tibetan listener completing 20 tasks. A future study should recruit listeners from Amdo, U-Tsang, and Kham backgrounds, balance familiarity with the evaluated dialects, and retain overlapping assignments for formal inter-rater agreement. Appendix C specifies a prospective design linking listener ratings to objective predictions.
- Transfer across generators. uses a closed-form clean latent in continuous flow matching, and requires reliable target-side language or dialect control symbols. Tests on autoregressive systems with discrete codec tokens and other conditioning architectures would establish the scope of transfer for the diagnostic findings and interventions.
6.6. Reproducibility and Resource Scope
The manuscript reports the data partitions, model configurations, selection rules, generation settings, metric definitions, and statistical procedures used in the experiments. Project-specific recordings and experimental artifacts, including model checkpoints, evaluation manifests, per-utterance predictions, generated speech, and Tibetan ASR resources, are not publicly released because of upstream licenses, recording consent, speaker privacy, and service constraints. Public datasets and pretrained models remain available from their cited sources. Aggregate results and the specifications required to assess the experimental design are provided in the article and appendices.
6.7. Ethical and Social Considerations
Generating arbitrary content in a person’s voice and a specified dialect creates risks of impersonation, fraud, and fabricated speech attributed to minority communities. Future releases should document recording licenses and informed consent, remove identifying metadata where possible, and assess watermarking, synthetic-speech detection, and controlled access. The dialect-associated information in the x-vector probe also motivates privacy review of speaker representations, independently of waveform release. Service-quality evaluation should report the three Tibetan dialects separately and prioritize Kham coverage before deployment.
7. Conclusions
This study provides a diagnostic account of reference-side language and dialect leakage in dots.tts across Amdo, U-Tsang, and Kham Tibetan; Mandarin Chinese; and English. The protocol combines a 120-condition main matrix with five fixed reference prompts, a 30-task stress test with ten reference recordings and six new target texts, speaker-disjoint waveform evaluation, representation probing, matched training controls, and inference interventions. Language-level evaluation achieves a test macro-F1 of 0.976; the Tibetan-subset macro-F1 of 0.644 defines the dialect-level results as exploratory. An independent self-supervised representation audit reaches a dialect macro-F1 of while retaining strong source information, supporting continued use of the with explicit dialect-level qualification.
Within this matrix, disabling prompt latent prefill reduces Base O-ALR from 0.262 to 0.095 while O-DLR remains 0.222. The crossed-cluster 95% interval for the language-level difference, , captures substantial uncertainty across the available prompt and text clusters. The x-vector probe achieves 0.672 dialect-classification accuracy under a speaker-metadata-group-disjoint split, identifying dialect-decodable information in a representation that also carries speaker, source, and channel variation.
The tested interventions show no consistent improvement in target control. Reference x-vector re-pairing provides no stable benefit over the budget-matched continuation. All tested intermediate prompt-gating scales fall outside the joint target-control, speaker-similarity, and intelligibility criteria, while classifier guidance at reduces speaker similarity and increases Tibetan CER with an unchanged target-dialect hit rate. In the expanded-reference stress test, all nine block-by-time prompt-path masks have confidence intervals crossing zero; the large task-level changes identify direct prompt attention as an active pathway, but no fixed masks transfer stably across prompt and text clusters. These results define the observed control–fidelity and stability limits of the evaluated configurations.
English-reference-to-Tibetan synthesis is the most concentrated failure route in the fixed-reference matrix. The 20-task exploratory evaluation by one native Tibetan listener supplies corresponding accent and error descriptions. This route provides a concrete focus for target-side conditioning and input-dependent reference-access design. Evaluation with verified independent reference speakers, stronger source- and channel-disjoint dialect measures, and listeners balanced across dialect backgrounds will establish how these diagnostic findings extend across speakers and recording conditions.
Author Contributions
Conceptualization, T.D.; methodology, T.D.; software, T.D.; validation, T.D.; formal analysis, T.D.; investigation, T.D.; data curation, T.D.; writing—original draft preparation, T.D.; writing—review and editing, T.D., D.L. and Z.L.; visualization, T.D.; project administration, T.D.; supervision, D.L. and Z.L. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Institutional Review Board Statement
Not applicable. This study used publicly available recorded speech data; the exploratory listening evaluation comprised informal case-level judgments from one native Tibetan listener and was not conducted as a formal human-subject study.
Informed Consent Statement
Not applicable. All recorded speech used in this study was obtained from publicly available datasets under their respective licenses; no speech was newly recorded from human participants.
Data Availability Statement
Project-specific recordings and experimental artifacts, including model checkpoints, evaluation manifests, per-utterance predictions, generated speech, and Tibetan ASR assets, are not publicly released because of recording licenses, consent, speaker privacy, and upstream model terms. Public datasets and pretrained models remain available from their cited sources. Aggregate results and the methodological and statistical specifications needed to assess the study are reported in the article and appendices.
Conflicts of Interest
The authors declare no conflicts of interest.
Appendix A. Objective Evaluator Validity
Table A1 summarizes the split audit.
Table A1.
Five-class split audit. The predecessor is excluded because of speaker overlap. The revised split is speaker-disjoint but not source- or channel-disjoint.
The speaker-disjoint waveform evaluator () is a waveform-level classifier for Amdo, U-Tsang, Kham, standard Mandarin, and standard English. Its input is a fixed four-second, 80-bin log-mel representation, and generated speech is never used for training. Re-examination of the excluded predecessor’s manifests found 1651 shared speaker identifiers between training and validation, 1696 between training and test, and 1196 between validation and test. Almost all 10,000 test utterances came from speakers seen during training. Aggregate identifiers such as zeta_kham_prepare_kham_unknown also incorrectly pooled many unknown speakers into one identity. Its accuracy and macro-F1 of 0.9775 and 0.9776 therefore describe performance with speaker overlap. All reported leakage comparisons use the .
For the , all available natural speech was pooled by verified spk identity and split at the group level. Unknown and *_unknown aggregate identities were excluded. Speaker round-robin allocation and a per-speaker row cap prevented long speakers from dominating. The final training, validation, and test partitions contain 69,424/9125/9008 utterances and 2329/292/292 speakers. Pairwise speaker and utterance overlap is zero; aggregate-speaker rows and training-seen speaker rows in validation and test are also zero.
The partitions share seven data sources and their associated recording conditions. Three component classifiers with identical architectures were trained with random seeds 20260821, 20260822, and 20260823. Epochs 8, 5, and 13 were selected only by validation macro-F1, and the averages their class probabilities.
On the test set, ensemble five-class accuracy/macro-F1 is 0.837/0.774, and language-level accuracy/macro-F1 after collapsing Tibetan dialects is 0.978/0.976. Per-class F1 is 0.842 for Amdo, 0.748 for U-Tsang, 0.330 for Kham, 0.969 for Mandarin, and 0.980 for English. Source-level accuracy ranges from 0.316 for tibetan_dialect_synthesis to 0.994 for librispeech_hf, indicating substantial source or channel shift. Figure A1 shows that Kham is mainly confused with Amdo and U-Tsang, while cross-language errors are uncommon.
Independent Self-Supervised Representation Sensitivity Audit
The independent audit contains 5671 unique natural-speech recordings across three frozen cohorts. The dialect cohort contains 1849 Tibetan utterances and uses the recording source as the group key. Its train, development, and held-out partitions contain 24, 9, and 9 source groups, respectively, with zero source overlap. Four sources containing multiple dialect labels are kept intact within one partition rather than treated as verified cross-dialect recordings from the same speaker. A separate matched-text cohort contains 1902 recording pairs, and nine existing Full/x-vector-only intervention pairs are reserved for ordering calibration.
Frozen HuBERT [32] layers 6, 9, and 12 and XLS-R [33] layers 6, 12, 18, and 24 are summarized by utterance-level temporal mean and standard deviation. For seeds 1201, 1202, and 1203, the audit standardizes each representation and fits balanced logistic regression (, maximum 1000 iterations); the dialect probe uses source-group-equal sample weights. Seven candidates are ranked using only train/development data by Equation (A1):
where is content concordance. For K development source classes and source-decoding macro-F1 , normalized source invariance is defined in Equation (A2):
where . HuBERT layer 9 ranks first with a development dialect macro-F1 of 0.6253, content concordance of 0.8856, source macro-F1 of 0.9728, and composite score of 0.5845. The selected layer is locked before a single held-out evaluation.
On held-out source groups, HuBERT layer 9 obtains a dialect accuracy of and macro-F1 of . The matched-text content concordance is . An auxiliary classifier trained to recover the nine held-out sources reaches a source macro-F1 of , compared with the uniform baseline of 0.1111. Values are means ± standard deviations across the three seeds. Among the nine ordering-calibration pairs, five move in the expected target-centroid direction and six in the expected target-probability direction. The audit therefore detects dialect information alongside strong source information. Because the cohorts differ, their F1 values and the primary evaluator’s Tibetan-subset F1 are not a formal paired comparison. No class-level estimate from this audit supports a stronger Kham claim.
Figure A1.
Five-class confusion matrix for the three-model ensemble on the speaker-disjoint test set (). Color encodes row-normalized recall; each cell reports the raw count and within-class percentage. Only 25% of Kham utterances are correctly classified, with 41% assigned to U-Tsang and 30% to Amdo. Mandarin and English recall is 97% and 99%, respectively, confirming that the language-level proxy is stronger than the Tibetan dialect-level proxy.
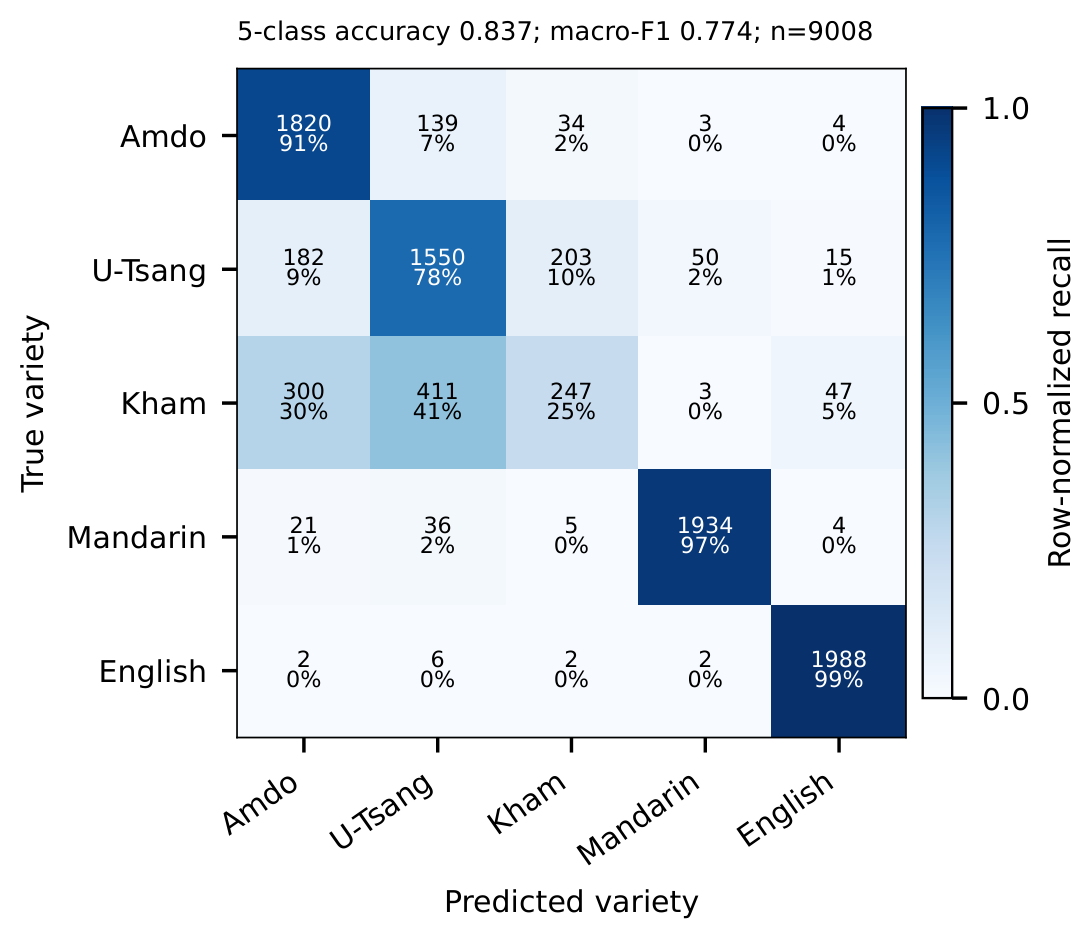
After freezing, 16 manifests containing 1752 generated utterances were rescored: fourteen 120-condition manifests covering Base, , , and controls, plus 72 English-reference-to-Tibetan prompt-scale utterances. The predictions were stored separately from those of the excluded evaluator. All manifests completed with their expected row counts.
Appendix B. Training, Generation, and Frozen Configuration
Appendix B.1. Training and Checkpoint Selection
Base adaptation uses the dots.tts-soar-tibetan-unicode pretrained model and a precomputed-feature manifest. The 995,000 training rows comprise 249,000 each for Amdo, U-Tsang, and Kham and 124,000 each for Mandarin and English. Audio is sampled at 48 kHz. Base training uses seed 44, an initial learning rate of , a weight decay of 0.01, 50 warm-up steps, gradient accumulation of 2, and gradient-norm clipping at 1. Validation is performed every 100 steps on a balanced set containing all five varieties. The main Base experiment uses the step-3000 checkpoint.
The and unmodified Base manifests have equal length. Pairing seed 48 selects 149,062 of 995,000 rows (14.98%) for reference x-vector replacement; every replacement is cross-speaker and cross-variety. The remaining 845,938 rows retain the target sample’s original x-vector. and matched Base both continue from Base@3000 using training seed 47, an initial learning rate of , a weight decay of 0.01, 50 warm-up steps, gradient accumulation of 2, and a 2000-step budget. Their only intended difference is the training manifest.
Both continuations have 21 validation records at steps 0, 100, …, 2000. At each step, the selection score is the unweighted mean of source-level flow-matching-plus-EOS validation losses for Amdo, U-Tsang, Kham, Mandarin, and English. reaches the lowest score, 0.738430369, at step 1400; the next scores are 0.742038369 at step 1700 and 0.743186355 at step 2000. Matched Base is evaluated at the same step to hold the update count fixed. Its step-1400 score, 0.736611021, is also its minimum. The generation matrix, , , ASR, and listening data were not inspected for this selection.
Appendix B.2. Speaker X-Vector Extraction
The dots.tts SpeakerXVectorFeatures module uses 3D-Speaker’s CAMPPlus implementation of CAM++. Prompt audio is loaded at its native rate as mono, trimmed at the leading and trailing boundaries with top_db=30, and resampled with high-quality band-limited interpolation to the model’s 48 kHz rate. The speaker branch is then resampled to 16 kHz, and an 80-bin Kaldi filterbank with a 25 ms window, 10 ms shift, dither=0, and per-bin temporal mean normalization is computed. CAM++ combines a front convolution module with dense time-delay neural network (TDNN) blocks and returns a 512-dimensional vector. The output is not -normalized before the speaker projection.
The extractor uses at most 10 s of trimmed audio and would select a random 10 s crop for a longer prompt. The five frozen prompt durations after trimming are 5.547, 5.472, 9.888, 6.101, and 6.101 s; no crop was activated. At generation, the vector is multiplied by speaker scale 1.5 and projected into the global conditioning stream.
Appendix B.3. Latent Classifier for CGD
The guidance classifier receives the normalized dots.tts acoustic latent with 128 channels. Training examples are random crops of 1–8 four-frame patches (4–32 frames), while decoding queries a single current four-frame clean-latent estimate. Two 1D convolutions map 128→256 and 256→256 with kernel size 5 and GELU activations. Temporal mean and standard deviation are concatenated, followed by a 512→256→5 MLP. The resulting model has approximately 0.5 million parameters and predicts Amdo, U-Tsang, Kham, Mandarin, or English.
The source manifests contain 995,000 training and 50,000 validation rows. Balanced subsets use 12,000 utterances per class for training (60,000 total) and 800 per class for validation (4000 total). Utterance–identifier overlap is zero. The split is not speaker-disjoint: 2455 of 2460 validation speaker identifiers occur among the 2923 training identifiers, and recording sources overlap. Training uses six epochs, a batch size of 256, AdamW with learning rate and weight decay , cosine decay, at most 200 warm-up steps, cross-entropy, gradient clipping at 1, and seed 42.
The selected epoch minimizes the error on validation single-patch inputs, matching the signal used by . Single-patch accuracy is 0.775972 over 163,676 patches; full-sequence accuracy is 0.98025 over 4000 utterances. Full-sequence recalls are 0.93625 for Amdo, 0.99875 for U-Tsang, 0.97625 for Kham, 0.99625 for Mandarin, and 0.99375 for English. This checkpoint supplies the guidance gradient. Outcome evaluation uses the separate described in Appendix A.
Appendix B.4. Generation and Prompt-Gating Screen
All systems generate the same condition keys with seed 42, ten Euler steps, classifier-free guidance of 1.2, and speaker scale 1.5. The prompt-scale experiment changes only prompt_prefill_scale within the gated prompt path. A gated setting retains the prompt transcript and its sequence positions; x-vector-only disables that path and is not a retained-sequence scale-zero condition. Objective analysis first deduplicates by reference prompt, target variety, and target-text identifier and then pairs shared keys. All objective results reported in the article use the ; predictions from the excluded speaker-overlapping evaluator are outside the analysis.
The focused English-reference-to-Tibetan configuration was frozen before generation and scoring. Its expansion screen requires at least 6/9 target-language hits, a positive mean target-minus-reference probability margin, mean of , and mean Tibetan CER of . Six hits require correct language assignment in at least two thirds of the route cases; the margin uses its natural zero boundary. The floor lies between the frozen Full and x-vector-only endpoints (0.827/0.771 for Base and 0.840/0.735 for ). The CER ceiling matches the weaker x-vector-only endpoint to two decimals (0.149 for Base and 0.121 for ). These are operational expansion criteria rather than universal cutoffs. Independently of the thresholds, no intermediate scale matches the Full endpoint’s together with the x-vector-only endpoint’s target-hit count and CER.
Appendix B.5. Expanded-Reference Prompt-Path Stress Test
The frozen stress-test manifest contains 30 tasks: 12 cross-language conflicts, 12 cross-dialect conflicts, and 6 same-variety safety cases. Ten distinct reference recordings provide two prompts per variety; nine do not occur in the main matrix. Six target texts are selected by stable hashing from the validation manifest after excluding all main-matrix target texts and all prompt transcripts. The @1400 generator uses seed 260830, ten Euler steps, classifier-free guidance of 1.2, and a speaker scale of 1.5.
For each of nine fixed block-by-time cells, the implementation masks only current-latent-query attention to prompt-latent keys. Blocks 0–5, 6–11, and 12–17 define early, middle, and late model groups; steps 0–2, 3–6, and 7–9 define early, middle, and late solver windows. The x-vector, text inputs, prompt sequence, history, noise, and solver remain unchanged. Baseline and each mask complete 30/30 tasks. Three empty-mask no-op waveforms are bit-identical to their paired baselines. The primary statistic and 10,000-replicate crossed-cluster bootstrap use the 24 conflict tasks, reference prompt, and target-text identifier. None of the nine cells passes the frozen advancement criteria, so the separate confirmation set remains unopened.
Appendix B.6. Independent Self-Supervised Representation Audit
The independent self-supervised representation audit freezes 5671 unique natural-speech recordings and mean–standard-deviation pooled features from HuBERT layers 6/9/12 and XLS-R layers 6/12/18/24. The 1849-utterance Tibetan cohort is divided into 24/9/9 source groups for train/development/held-out evaluation with zero source overlap. Balanced logistic regression uses random seeds 1201, 1202, and 1203, , and at most 1000 iterations; the dialect probe uses source-group-equal sample weights. Candidate ranking uses only train/development results; HuBERT layer 9 is locked before held-out evaluation. Appendix A reports the development and held-out results.
Appendix B.7. ASR Decoding and Text Normalization
Mandarin and English are transcribed with Whisper large-v3 using openai-whisper==20231117. The target language is forced to zh or en, temperature is 0, half-precision inference is used on a GPU, and other decoding arguments retain the package defaults. Mandarin reference and hypothesis strings are stripped of all whitespace, ASCII punctuation, and common Chinese punctuation before character-level CER. English strings are converted to lowercase; characters outside a–z, digits, apostrophes, and whitespace are mapped to spaces; and repeated spaces are collapsed before word-level WER.
The Tibetan recognizer is an internally developed, proprietary, unpublished Zipformer-based transducer deployed through sherpa-onnx. This model was reported to achieve 87–93% comprehensive recognition accuracy across the three Tibetan dialects. Separately, an Amdo Zipformer trained on 535.9 h of speech reported a WER of 14.14% for the best epoch-15 seven-checkpoint average. Both figures are pre-export results. The deployed recognizer uses the epoch-30-avg-1 ONNX assets; ONNX conversion may introduce a small accuracy loss, but the post-conversion difference has not been independently quantified.
The frozen inference package comprises encoder-epoch-30-avg-1.onnx, decoder-epoch-30-avg-1.onnx, joiner-epoch-30-avg-1.onnx, and tokens.txt; epoch-30-avg-1 is the internal asset label rather than a public model release. Input is converted to mono, 16 kHz, signed 16-bit waveform format. The feature configuration uses 80 bins, a 20 Hz lower bound, an upper bound 400 Hz below Nyquist, and zero dither. Decoding uses greedy_search, max_active_paths=4, CUDA, one central-processing-unit (CPU) thread, no language model, no hotwords, a blank penalty of 0, and modeling_unit=cjkchar. Tibetan normalization removes whitespace, shad-family sentence delimiters, and ASCII punctuation while retaining the tsheg. All CER and WER calculations use jiwer==4.0.0. Code-mixed items are excluded.
Appendix B.8. Waveform Evaluator
The is a four-stage residual convolutional neural network (CNN) ensemble with 32 base channels and a dropout of 0.2 in each component model. Input audio is resampled to 16 kHz and represented by a four-second, 80-bin log-mel spectrogram using a 25 ms window and 10 ms hop. Each seed uses a batch size of 256, an initial learning rate of , a weight decay of , a maximum of 40 epochs, patience 8, automatic mixed precision, and class-weighted cross-entropy without a balanced sampler. Checkpoints are selected only by validation macro-F1; the selection results are reported in Appendix A.
Appendix C. Exploratory Listening-Evaluation Record
The frozen listening set contains 20 anonymized paired comparisons, including 14 cross-lingual and six Tibetan cross-dialect tasks. One text is retained for each reference–target condition. One native Tibetan listener completed all tasks. For target control/reference-side leakage, was preferred in six tasks, Base in seven, and seven were tied. For naturalness and clarity, was preferred in five, Base in seven, and eight were tied. All 20 speaker-timbre comparisons were tied. English-reference-to-Amdo, -Kham, and -U-Tsang tasks were annotated as showing similarly clear leakage in both systems, with a severe English accent specifically noted for Kham and U-Tsang.
This exploratory record supports route screening and qualitative error attribution. Its counts describe one listener’s judgments on the frozen tasks; listener-population effects and inter-rater agreement require additional independent raters.
A future confirmatory study should sample listeners from Amdo, U-Tsang, and Kham backgrounds and record their first dialect, long-term region of residence, and familiarity with each evaluated dialect. Assignment should balance dialect familiarity across systems and include shared items rated by multiple listeners within and across background groups. Prospective power analysis should determine the numbers of listeners, reference speakers, and texts from a prespecified minimum meaningful effect. Randomized system order and anonymized samples should be combined with preregistered tie handling, invalid-response rules, and analysis stratified by listener background and target dialect.
This future design should collect separate judgments of target-language or target-dialect identity, reference-associated accent strength, naturalness, intelligibility, and speaker similarity. Inter-rater agreement should be reported separately for categorical assignments and ordered accent ratings, using statistics appropriate to each response scale and including uncertainty intervals. A crossed analysis of listeners and utterances can then compare systems and relate perceptual ratings to the objective predictions on the same synthesized samples. This design separates classifier accuracy on natural speech from its empirical correspondence with perceived leakage in synthesized speech.
References
- Zhang, W.; Yang, H.; Bu, X.; Wang, L. Deep learning for Mandarin–Tibetan cross-lingual speech synthesis. IEEE Access 2019, 7, 167884–167894. [Google Scholar] [CrossRef] [Scilit]
- Yang, H.; Oura, K.; Gan, Z.; Tokuda, K.; Wang, H. Using speaker adaptive training to realize Mandarin–Tibetan cross-lingual speech synthesis. Multimed. Tools Appl. 2015, 74, 9927–9942. [Google Scholar] [CrossRef] [Scilit]
- Wang, H.; Yang, H.; Gan, Z. Realizing Mandarin–Tibetan bilingual speech synthesis by speaker adaptive training. J. Tsinghua Univ. Sci. Technol. 2013, 53, 776–780. [Google Scholar]
- Guo, W.; Yang, H.; Gan, Z. A DNN-based Mandarin–Tibetan cross-lingual speech synthesis. In Proceedings of the APSIPA Annual Summit and Conference (APSIPA ASC), Honolulu, HI, USA, 12–15 November 2018; pp. 1702–1707. [Google Scholar]
- Yu, Q.; Liu, P.; Wu, Z.; Kang, S.; Meng, H.; Cai, L. Learning cross-lingual information with multilingual BLSTM for speech synthesis of low-resource languages. In Proceedings of the IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), Shanghai, China, 20–25 March 2016; pp. 5545–5549. [Google Scholar]
- Wang, Y.; Skerry-Ryan, R.J.; Stanton, D.; Wu, Y.; Weiss, R.J.; Jaitly, N.; Yang, Z.; Xiao, Y.; Chen, Z.; Bengio, S.; et al. Tacotron: Towards end-to-end speech synthesis. arXiv 2017, arXiv:1703.10135. [Google Scholar]
- Shen, J.; Pang, R.; Weiss, R.J.; Schuster, M.; Jaitly, N.; Yang, Z.; Chen, Z.; Zhang, Y.; Wang, Y.; Skerry-Ryan, R.J.; et al. Natural TTS synthesis by conditioning WaveNet on mel spectrogram predictions. In Proceedings of the IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), Calgary, AB, Canada, 15–20 April 2018. [Google Scholar]
- Wang, C.; Chen, S.; Wu, Y.; Zhang, Z.; Zhou, L.; Liu, S.; Chen, Z.; Liu, Y.; Wang, H.; Li, J.; et al. Neural codec language models are zero-shot text to speech synthesizers. arXiv 2023, arXiv:2301.02111. [Google Scholar]
- Le, M.; Vyas, A.; Shi, B.; Karrer, B.; Sari, L.; Moritz, R.; Williamson, M.; Manohar, V.; Adi, Y.; Mahadeokar, J.; et al. Voicebox: Text-guided multilingual universal speech generation at scale. arXiv 2023, arXiv:2306.15687. [Google Scholar]
- Du, Z.; Chen, Q.; Zhang, S.; Hu, K.; Lu, H.; Yang, Y.; Hu, H.; Zheng, S.; Gu, Y.; Ma, Z.; et al. CosyVoice: A scalable multilingual zero-shot text-to-speech synthesizer based on supervised semantic tokens. arXiv 2024, arXiv:2407.05407. [Google Scholar]
- Anastassiou, P.; Chen, J.; Chen, J.; Chen, Y.; Chen, Z.; Chen, Z.; Cong, J.; Deng, L.; Ding, C.; Gao, L.; et al. Seed-TTS: A family of high-quality versatile speech generation models. arXiv 2024, arXiv:2406.02430. [Google Scholar]
- Zhuoma, R.; Zhu, L. A dataset of Tibetan dialect speech synthesis. China Sci. Data 2022, 7, 20–29. [Google Scholar] [CrossRef] [Scilit]
- Liu, Y.; Zhang, Z.; Ma-bao, B.; Duojie, R.; Cai, Y.; Yu, Y.; Wang, X.; Gao, F.; Huang, C.; Tashi, N. FMSD-TTS: Few-shot multi-speaker multi-dialect text-to-speech synthesis for U-Tsang, Amdo and Kham speech dataset generation. arXiv 2025, arXiv:2505.14351. [Google Scholar]
- Liu, Y.; Zhang, Z.; Ma-bao, B.; Duojie, R.; Cai, Y.; Yu, Y.; Wang, X.; Gao, F.; Huang, C.; Tashi, N. TMD-TTS: A unified Tibetan multi-dialect text-to-speech framework. arXiv 2025, arXiv:2509.18060. [Google Scholar]
- He, J.; Wang, C.; Lian, J.; Cai, Y.; Li, Y.; Duojie, R.; Li, J. Tibetan-TTS: Low-resource Tibetan speech synthesis with large model adaptation. arXiv 2026, arXiv:2605.02496. [Google Scholar]
- Al-Radhi, M.S.; Csapó, T.G.; Németh, G. Continuous vocoder applied in deep neural network based voice conversion. Multimed. Tools Appl. 2019, 78, 33549–33572. [Google Scholar] [CrossRef] [Scilit]
- Zhong, J.; Richmond, K.; Su, Z.; Sun, S. AccentBox: Towards high-fidelity zero-shot accent generation. In Proceedings of the IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), Hyderabad, India, 6–11 April 2025. [Google Scholar]
- Annamdevula, R.; Tatawat, A.; Gudmalwar, A.P.; Shah, N.J.; Wasnik, P. CrossAccent-TTS: Cross-lingual accent-intensity controllable text-to-speech via disentangled speaker and accent representations. arXiv 2026, arXiv:2606.25403. [Google Scholar]
- Zhou, Y.; Tian, X.; Li, H. Language agnostic speaker embedding for cross-lingual personalized speech generation. IEEE/ACM Trans. Audio Speech Lang. Process. 2021, 29, 3427–3439. [Google Scholar] [CrossRef] [Scilit]
- Kim, J.-H.; Yang, H.-S.; Ju, Y.-C.; Kim, I.-H.; Kim, B.-Y.; Chung, J.S. CrossSpeech: Speaker-independent acoustic representation for cross-lingual speech synthesis. arXiv 2023, arXiv:2302.14370. [Google Scholar]
- Wu, J.; Chen, T.; Chen, M.; Hu, W.; Wang, S.; Xiao, J. Improving multilingual text-to-speech with mixture-of-language-experts and accent disentanglement. In Proceedings of the Interspeech, Kos Island, Greece, 1–5 September 2024; pp. 4968–4972. [Google Scholar]
- Hu, H.; Zhu, X.; He, T.; Guo, D.; Zhang, B.; Wang, X.; Guo, Z.; Jiang, Z.; Hao, H.; Guo, Z.; et al. Qwen3-TTS technical report. arXiv 2026, arXiv:2601.15621. [Google Scholar]
- Du, Z.; Gao, C.; Wang, Y.; Yu, F.; Zhao, T.; Wang, H.; Lv, X.; Wang, H.; Ni, C.; Shi, X.; et al. CosyVoice 3: Towards in-the-wild speech generation via scaling-up and post-training. arXiv 2025, arXiv:2505.17589. [Google Scholar]
- Dathathri, S.; Madotto, A.; Lan, J.; Hung, J.; Frank, E.; Molino, P.; Yosinski, J.; Liu, R. Plug and play language models: A simple approach to controlled text generation. arXiv 2019, arXiv:1912.02164. [Google Scholar]
- Kim, H.; Kim, S.; Yoon, S. Guided-TTS: A diffusion model for text-to-speech via classifier guidance. In Proceedings of the International Conference on Machine Learning (ICML), Baltimore, MD, USA, 17–23 July 2022; pp. 11119–11133. [Google Scholar]
- Bansal, A.; Chu, H.-M.; Schwarzschild, A.; Sengupta, S.; Goldblum, M.; Geiping, J.; Goldstein, T. Universal guidance for diffusion models. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Vancouver, BC, Canada, 18–22 June 2023; pp. 843–852. [Google Scholar]
- Yu, J.; Wang, Y.; Zhao, C.; Ghanem, B.; Zhang, J. FreeDoM: Training-free energy-guided conditional diffusion model. In Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), Paris, France, 2–6 October 2023; pp. 23117–23127. [Google Scholar]
- Chung, H.; Kim, J.; McCann, M.T.; Klasky, M.L.; Ye, J.C. Diffusion posterior sampling for general noisy inverse problems. In Proceedings of the International Conference on Learning Representations (ICLR), Kigali, Rwanda, 1–5 May 2023. [Google Scholar]
- Ganin, Y.; Ustinova, E.; Ajakan, H.; Germain, P.; Larochelle, H.; Laviolette, F.; Marchand, M.; Lempitsky, V. Domain-adversarial training of neural networks. J. Mach. Learn. Res. 2016, 17, 1–35. [Google Scholar]
- Alemi, A.A.; Fischer, I.; Dillon, J.V.; Murphy, K. Deep variational information bottleneck. In Proceedings of the International Conference on Learning Representations (ICLR), Toulon, France, 24–26 April 2017. [Google Scholar]
- Wang, H.; Zheng, S.; Chen, Y.; Cheng, L.; Chen, Q. CAM++: A fast and efficient network for speaker verification using context-aware masking. In Proceedings of the Interspeech 2023, Dublin, Ireland, 20–24 August 2023; pp. 5301–5305. [Google Scholar] [CrossRef] [Scilit]
- Hsu, W.-N.; Bolte, B.; Tsai, Y.-H.H.; Lakhotia, K.; Salakhutdinov, R.; Mohamed, A. HuBERT: Self-supervised speech representation learning by masked prediction of hidden units. IEEE/ACM Trans. Audio Speech Lang. Process. 2021, 29, 3451–3460. [Google Scholar] [CrossRef] [Scilit]
- Babu, A.; Wang, C.; Tjandra, A.; Lakhotia, K.; Xu, Q.; Goyal, N.; Singh, K.; von Platen, P.; Saraf, Y.; Pino, J.; et al. XLS-R: Self-supervised cross-lingual speech representation learning at scale. In Proceedings of the Interspeech 2022, Incheon, Republic of Korea, 18–22 September 2022; pp. 2278–2282. [Google Scholar] [CrossRef] [Scilit]
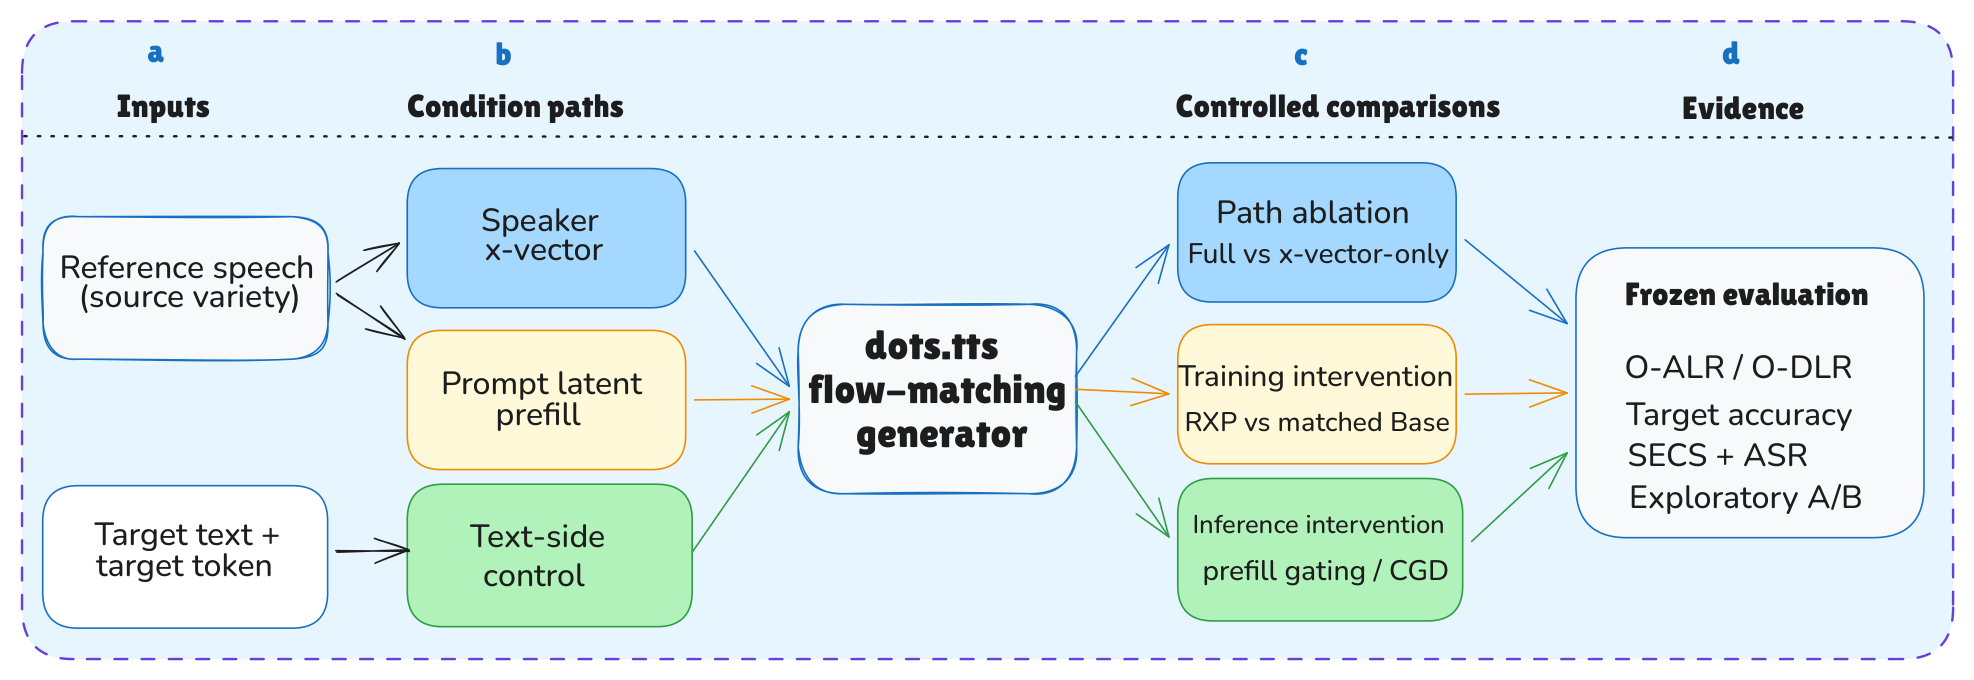
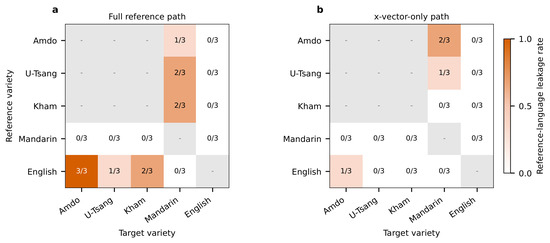
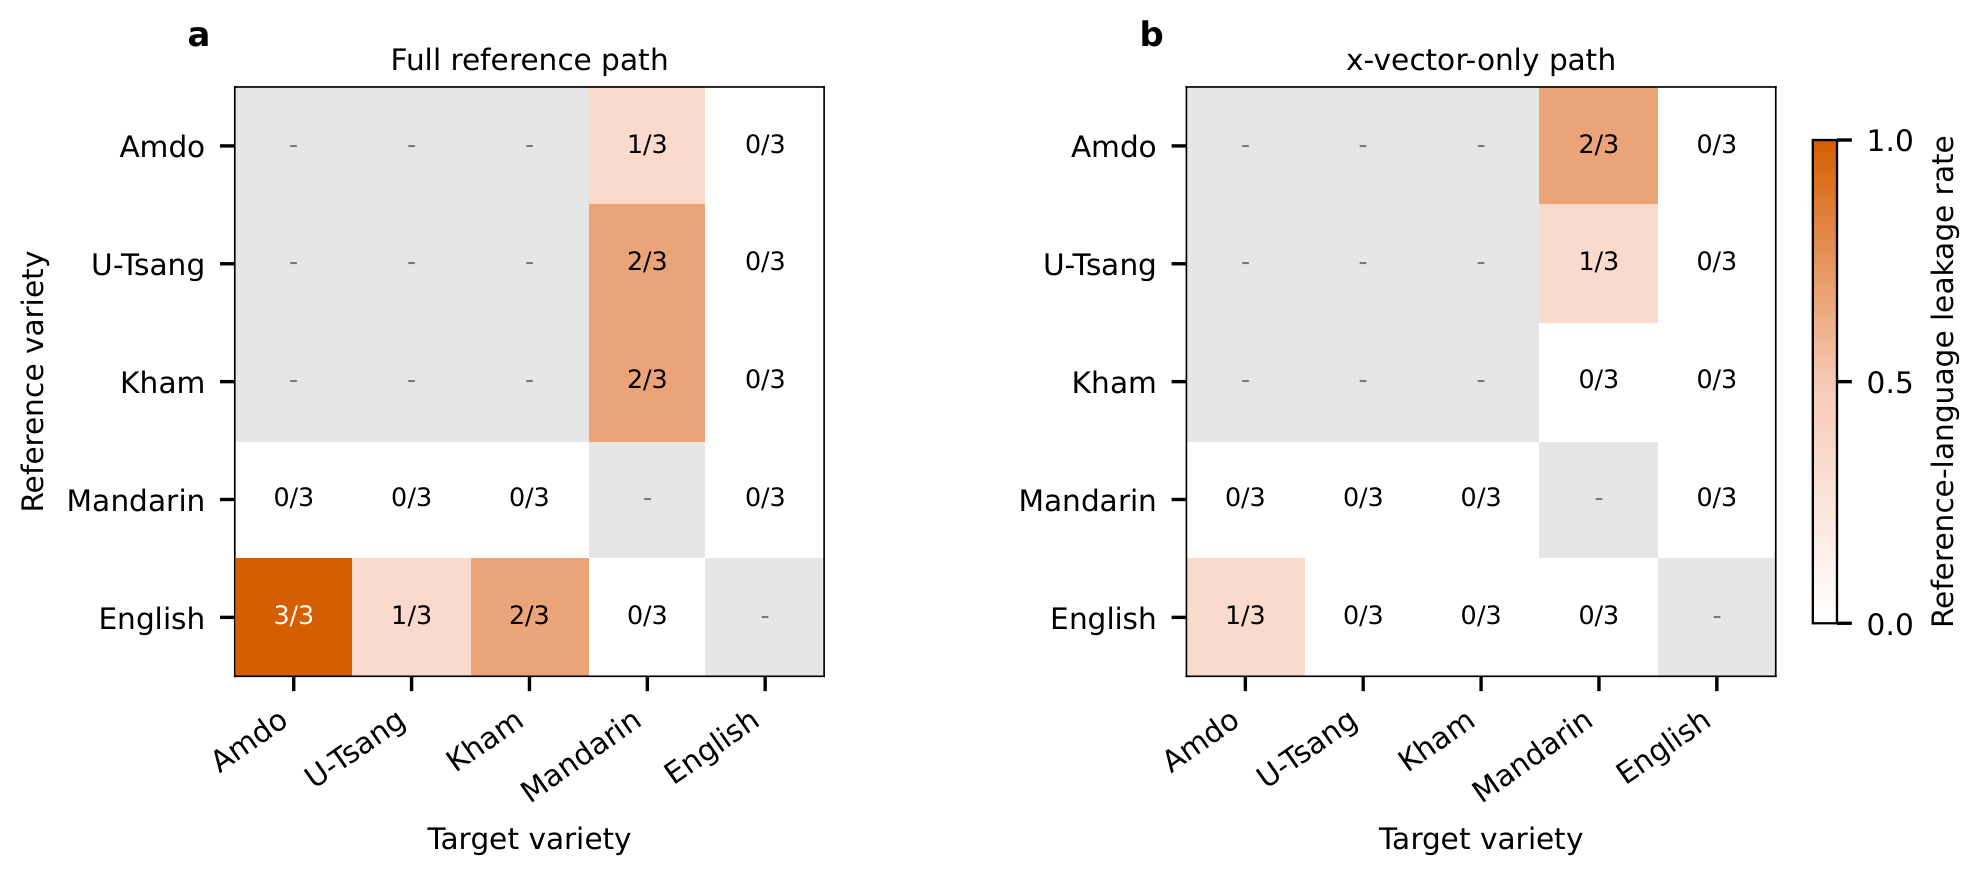
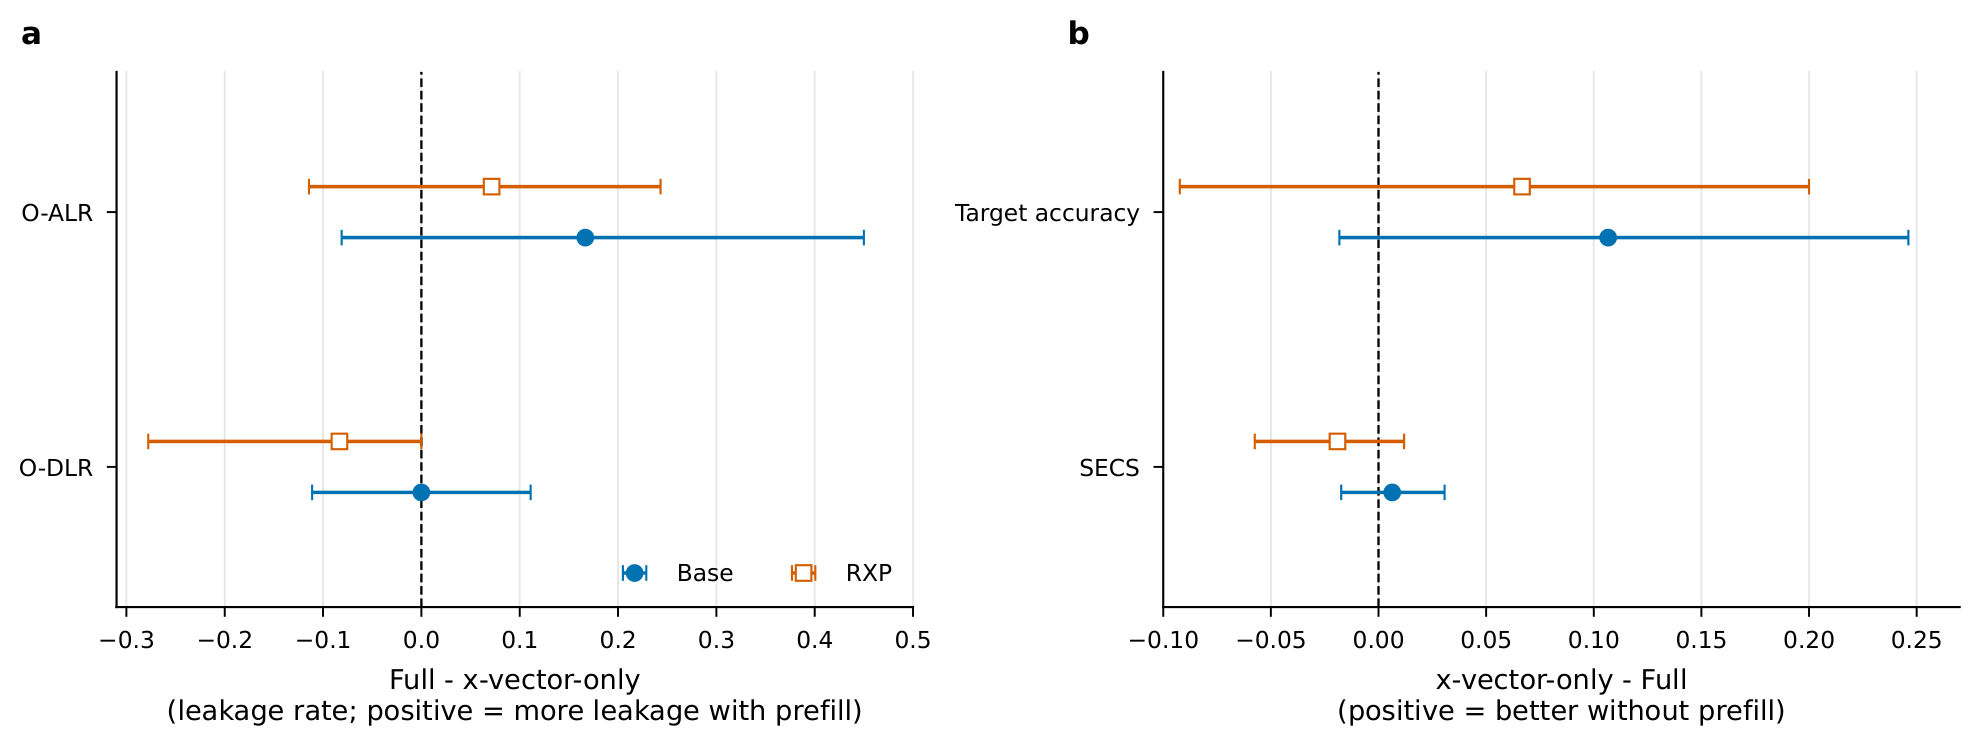
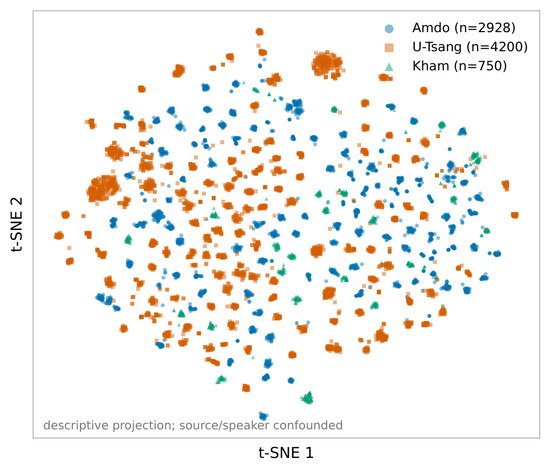
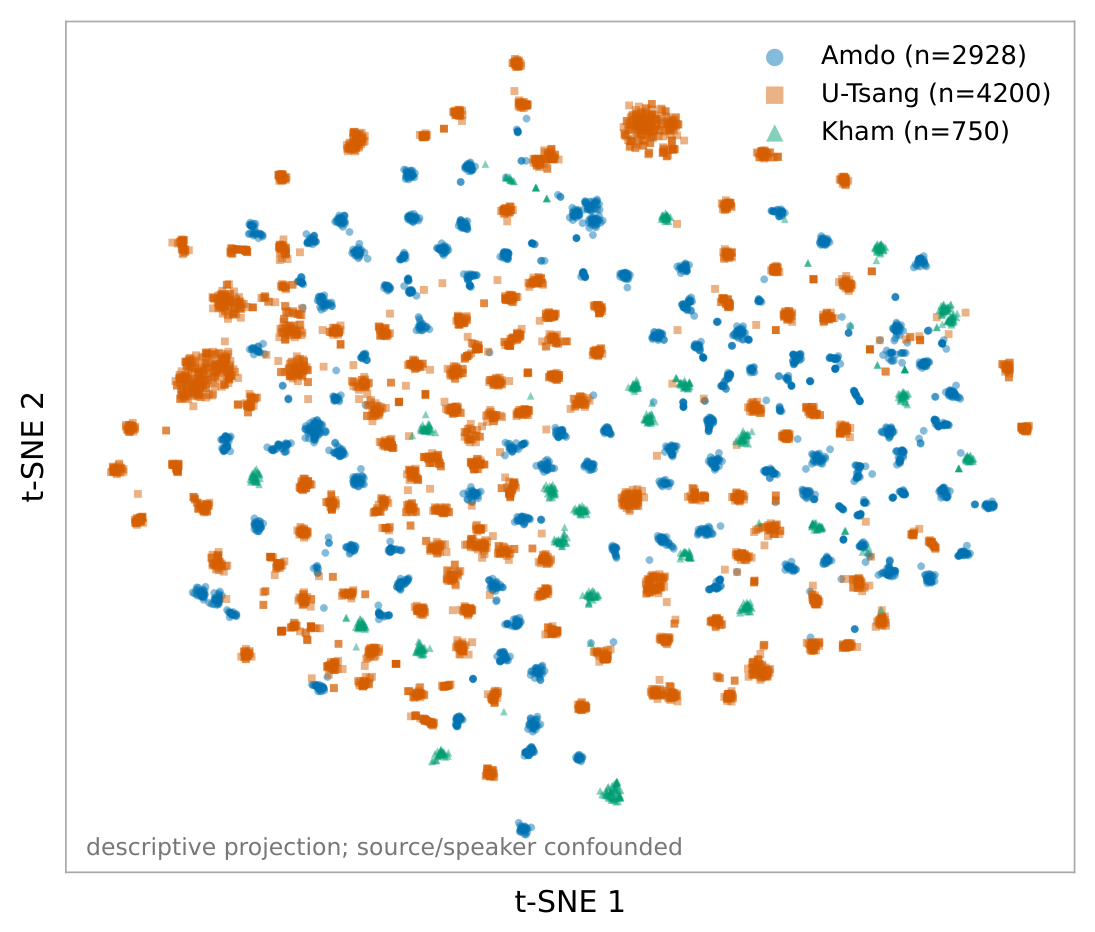
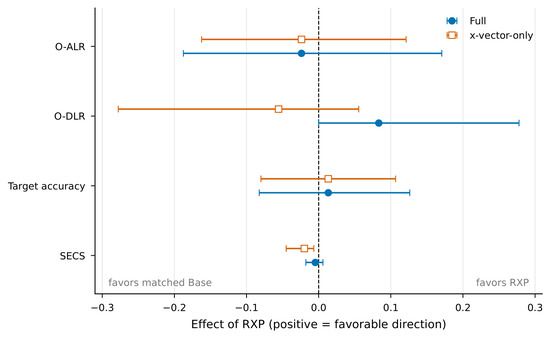
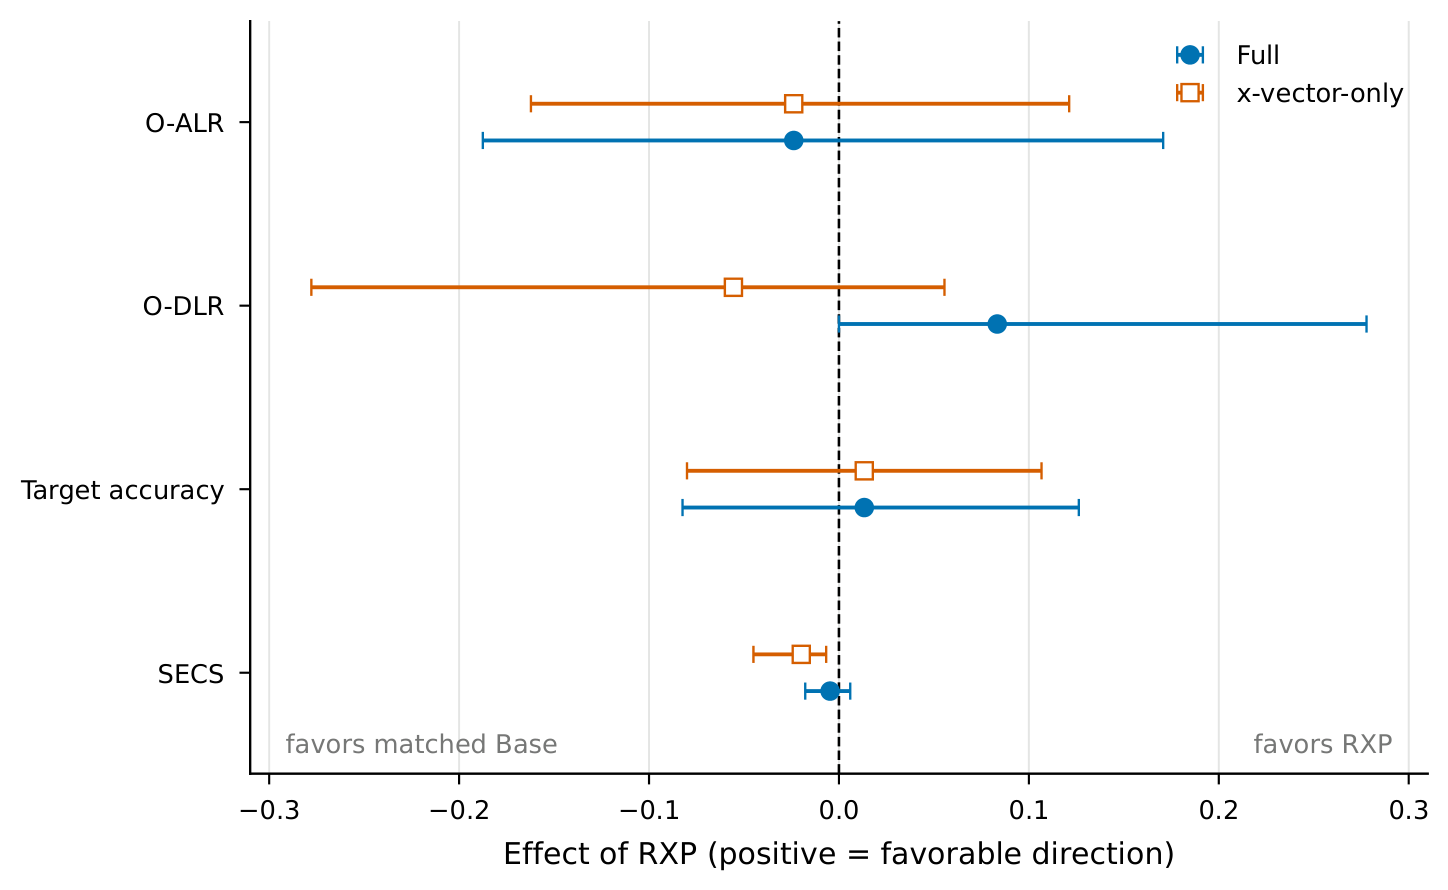
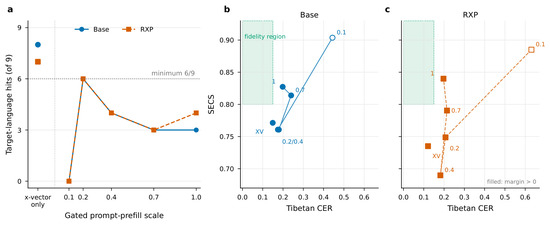
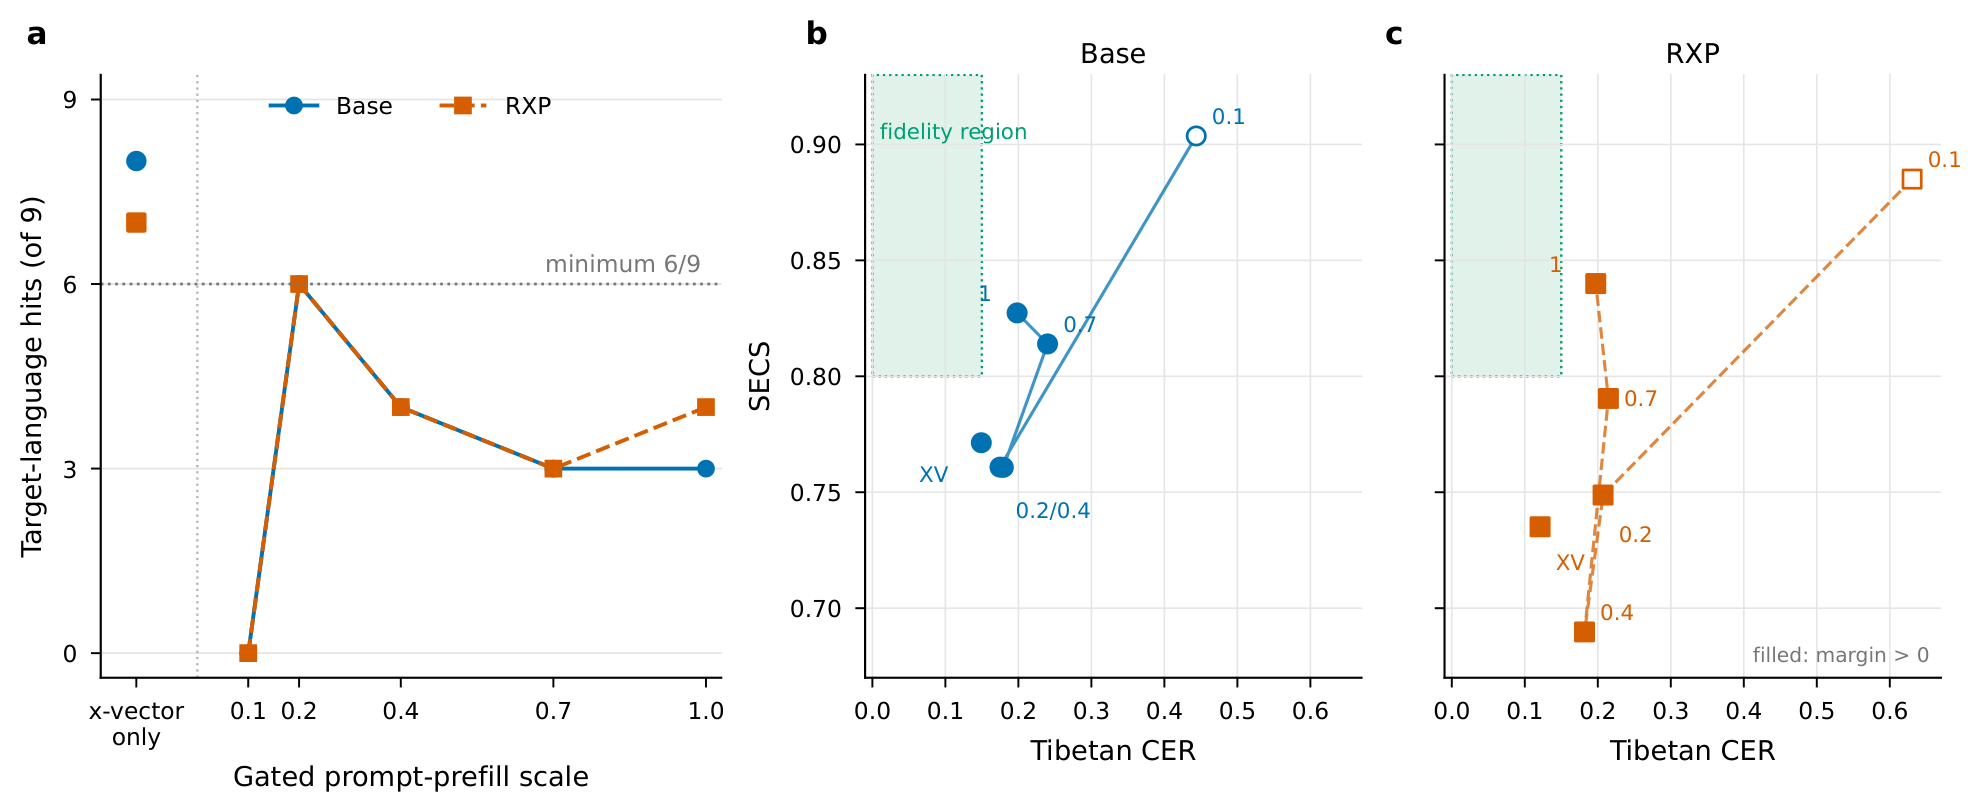
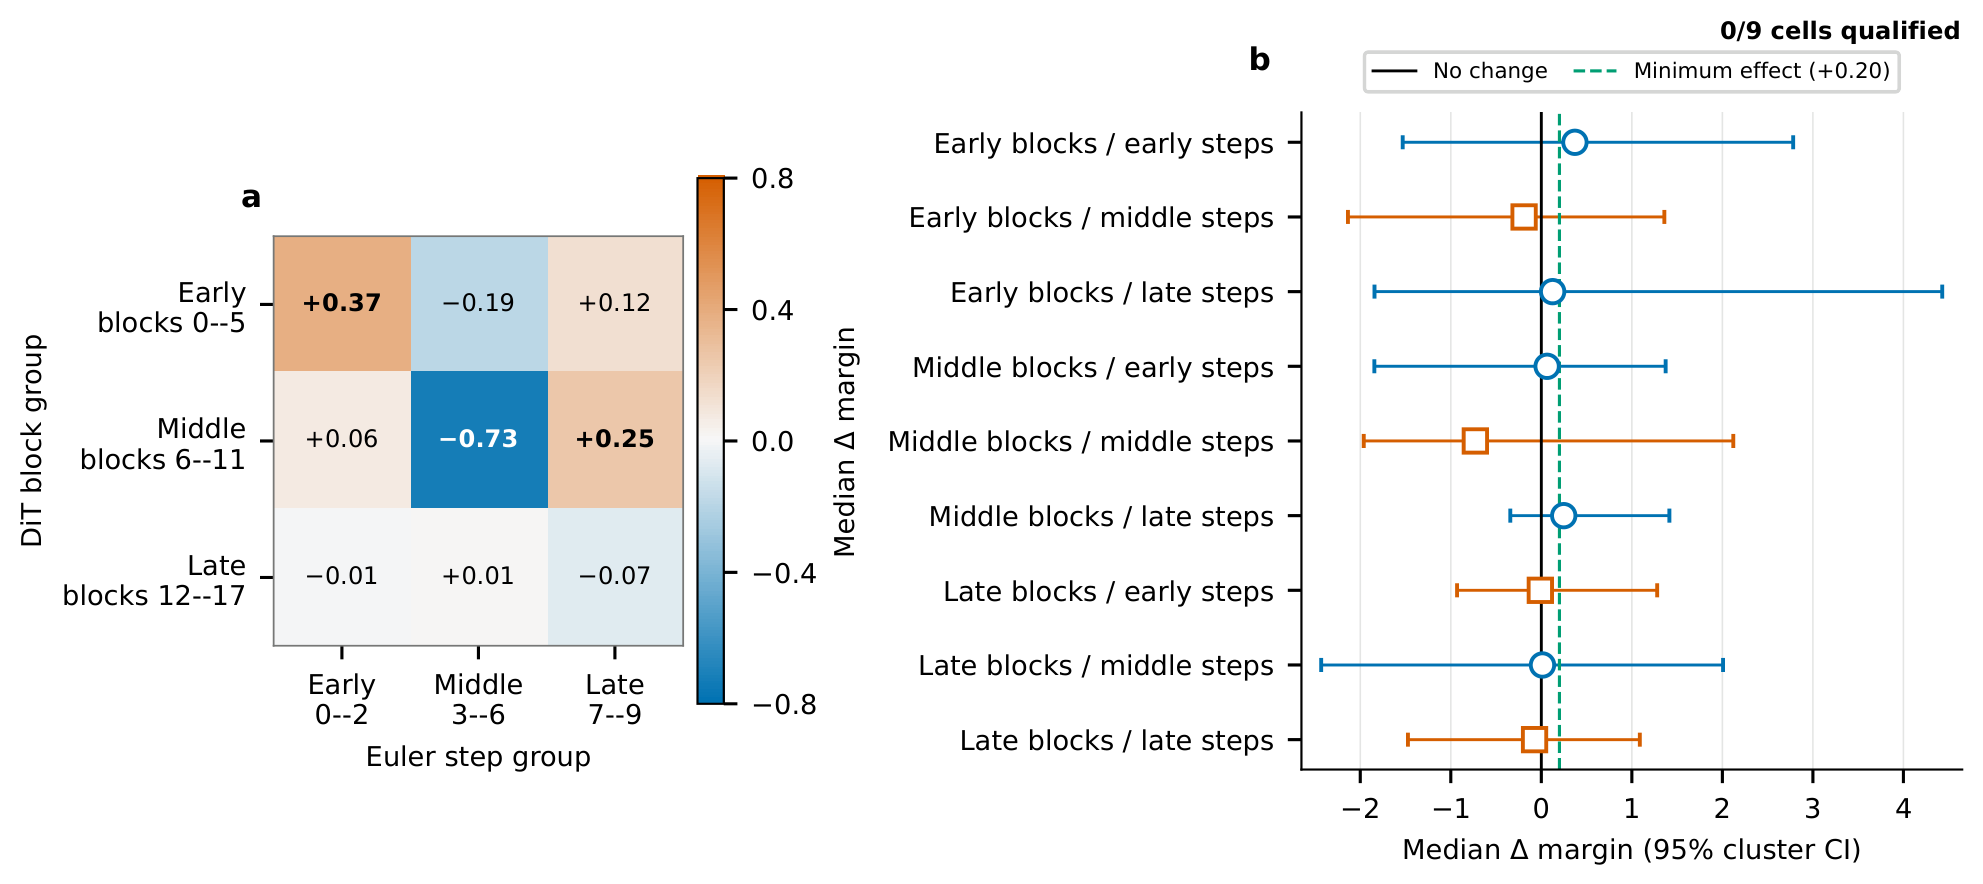
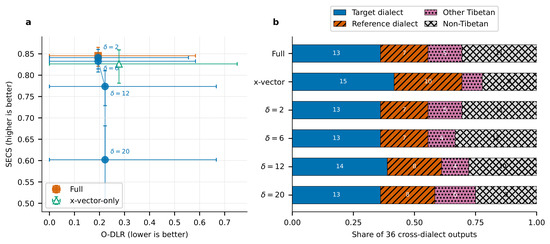
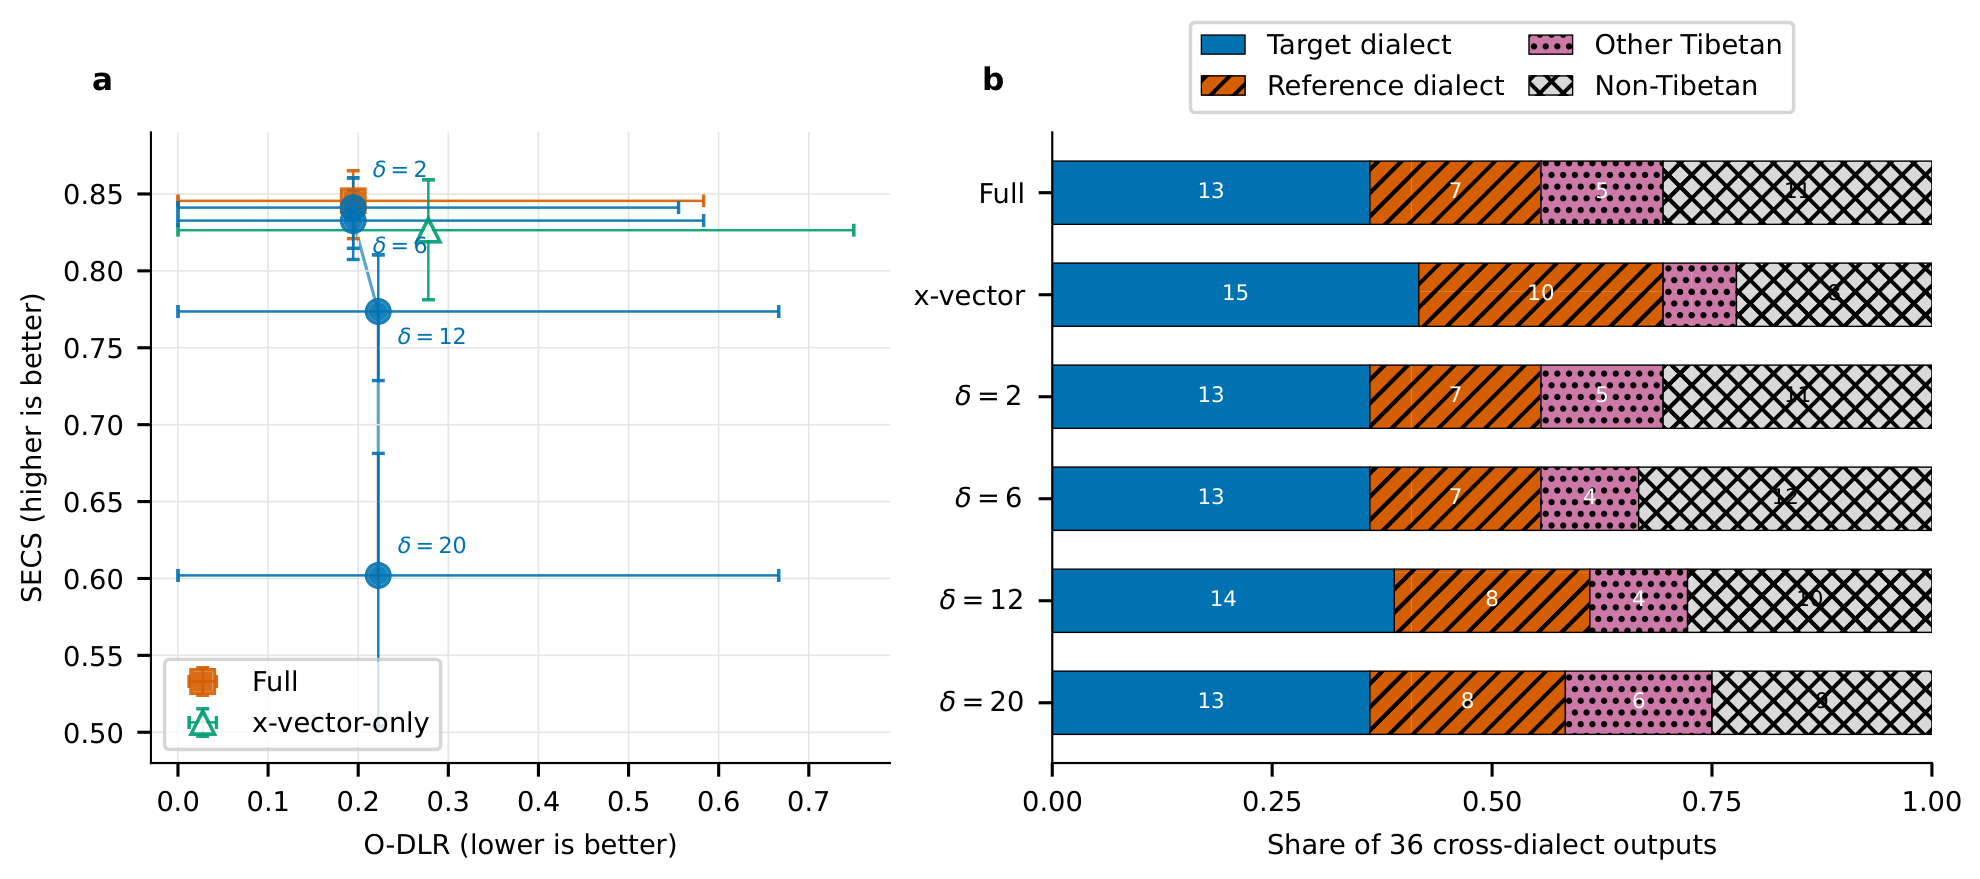

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.