


Abstract
Accurate prediction of residual flexural strengths is essential for the structural design and performance assessment of steel fibre reinforced concrete (SFRC). While machine learning models have recently demonstrated strong predictive capability, most of the existing approaches rely on heuristic feature selection, unconstrained architectures, and random validation splits that may overestimate generalisation capacity. This study proposes a Hard-Constrained Physics-Informed Neural Network (PCNN) for predicting the residual flexural strengths fR1–fR4 of steel fibre reinforced concrete (SFRC). Non-negativity, monotonic dependence on the reinforcement index, and bounded sequential evolution across crack mouth opening displacement (CMOD) stages are enforced architecturally through custom layers, guaranteeing mechanical admissibility by construction. The model was trained and validated on 235 original beam specimens from 18 experimental groups (expanded to 860 via controlled integer replication) using GroupKFold by Study cross-validation to eliminate data leakage. PCNN achieves fR1 MAE = 1.256 MPa and R2 = 0.606 across held-out experimental campaigns, competitive with Ridge Regression (MAE = 1.144, R2 = 0.688). Monotonicity audits show a 0% violation rate for PCNN versus 7.3% and 10.2% for Random Forest and GBDT, respectively. PCNN is the only model in the comparison that guarantees physical admissibility for all possible input configurations. The results demonstrate that embedding mechanical principles directly into neural network architecture enhances robustness and interpretability without compromising accuracy. The proposed Physics-Informed Neural Networks framework provides a transferable methodology for physics-guided machine learning in structural materials modelling.
1. Introduction
The use of steel fibre reinforced concrete (SFRC) in structural engineering has increased, mainly due to its ability to control cracks and provide post-cracking capacity. Based on research by Romualdi and Batson (1963) [1], its performance depends on discrete fibres arresting crack growth. This process was further defined through studies on fibre pull-out [2] and fracture mechanics [3]. Recent work focuses on sustainability; evidence suggests recycled steel fibres offer tensile benefits similar to commercial fibres but with lower embodied carbon [4]. For instance, ultra-high-performance concrete (UHPC) achieves its ductile behaviour and strain-hardening properties through the inclusion of steel fibres, which provide distributed bridging across the matrix [5,6].
Building upon these micromechanical foundations, the practical application of SFRC deviates from conventional reinforced concrete. Whereas tensile resistance is typically localised in discrete bars, SFRC provides distributed crack-bridging through randomly oriented fibres [7]. This mechanism is beneficial for industrial slabs, tunnel linings, and earthquake-resistant components, where serviceability and ultimate limit states are dictated by post-cracking performance.
To characterise this response, the present study defines the flexural behaviour of SFRC through residual strengths (fR1, fR2, fR3 and fR4), determined at specific crack mouth opening displacement (CMOD) intervals. These parameters, measured in accordance with EN 14651 [8], constitute the foundational data structure for the proposed Physics-Informed Neural Network (PINN) model. Although the model’s architecture is intrinsically coupled with this specific testing protocol, the framework establishes a versatile methodological basis. Consequently, the approach may be adapted to alternative standards, such as ASTM C1609 [9], thereby supporting the broader development of future PINN models based on varied experimental definitions of flexural performance.
Contemporary frameworks, such as the fib Model Code 2010 [10] and ACI 318-19 [11], incorporate residual strength-based formulations that enable the partial or full replacement of conventional reinforcement [12]. As these standards are progressively adopted globally—including the Spanish Structural Code [13] and Eurocode 8 [14]—the accurate prediction of residual strengths becomes essential for safe structural applications. Given the non-linear complexity of these parameters, identifying reliable predictive patterns is paramount for efficient structural design.
Unlike traditional concrete, where tensile resistance is localised in bars, SFRC provides distributed bridging through randomly oriented fibres. This mechanism is beneficial for industrial slabs, tunnel linings, and seismic components, where post-cracking behaviour governs serviceability and limit states. The flexural performance of SFRC is defined by residual strengths (fR1, fR2, fR3, and fR4), measured at specific CMOD levels according to EN 14651 (2007) [8]. These parameters quantify the capacity of cracked sections and form the basis for structural design. Contemporary frameworks, such as the fib Model Code 2010, use these formulations to determine the structural contribution of fibres, allowing for the partial or full replacement of conventional reinforcement. This approach is now integrated into international standards, including EN 1998-1 (2004) [14], ACI 318-19 (2019) (ACI Committee 318, 2019-ASTM C-1609) [11], and various European guidelines [13]. Consequently, predicting residual strengths accurately is fundamental for code-based application of SFRC.
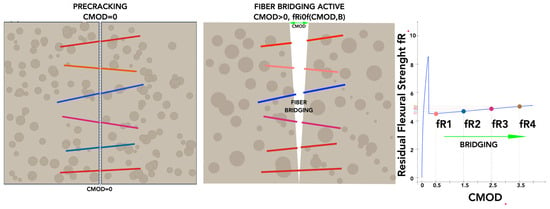
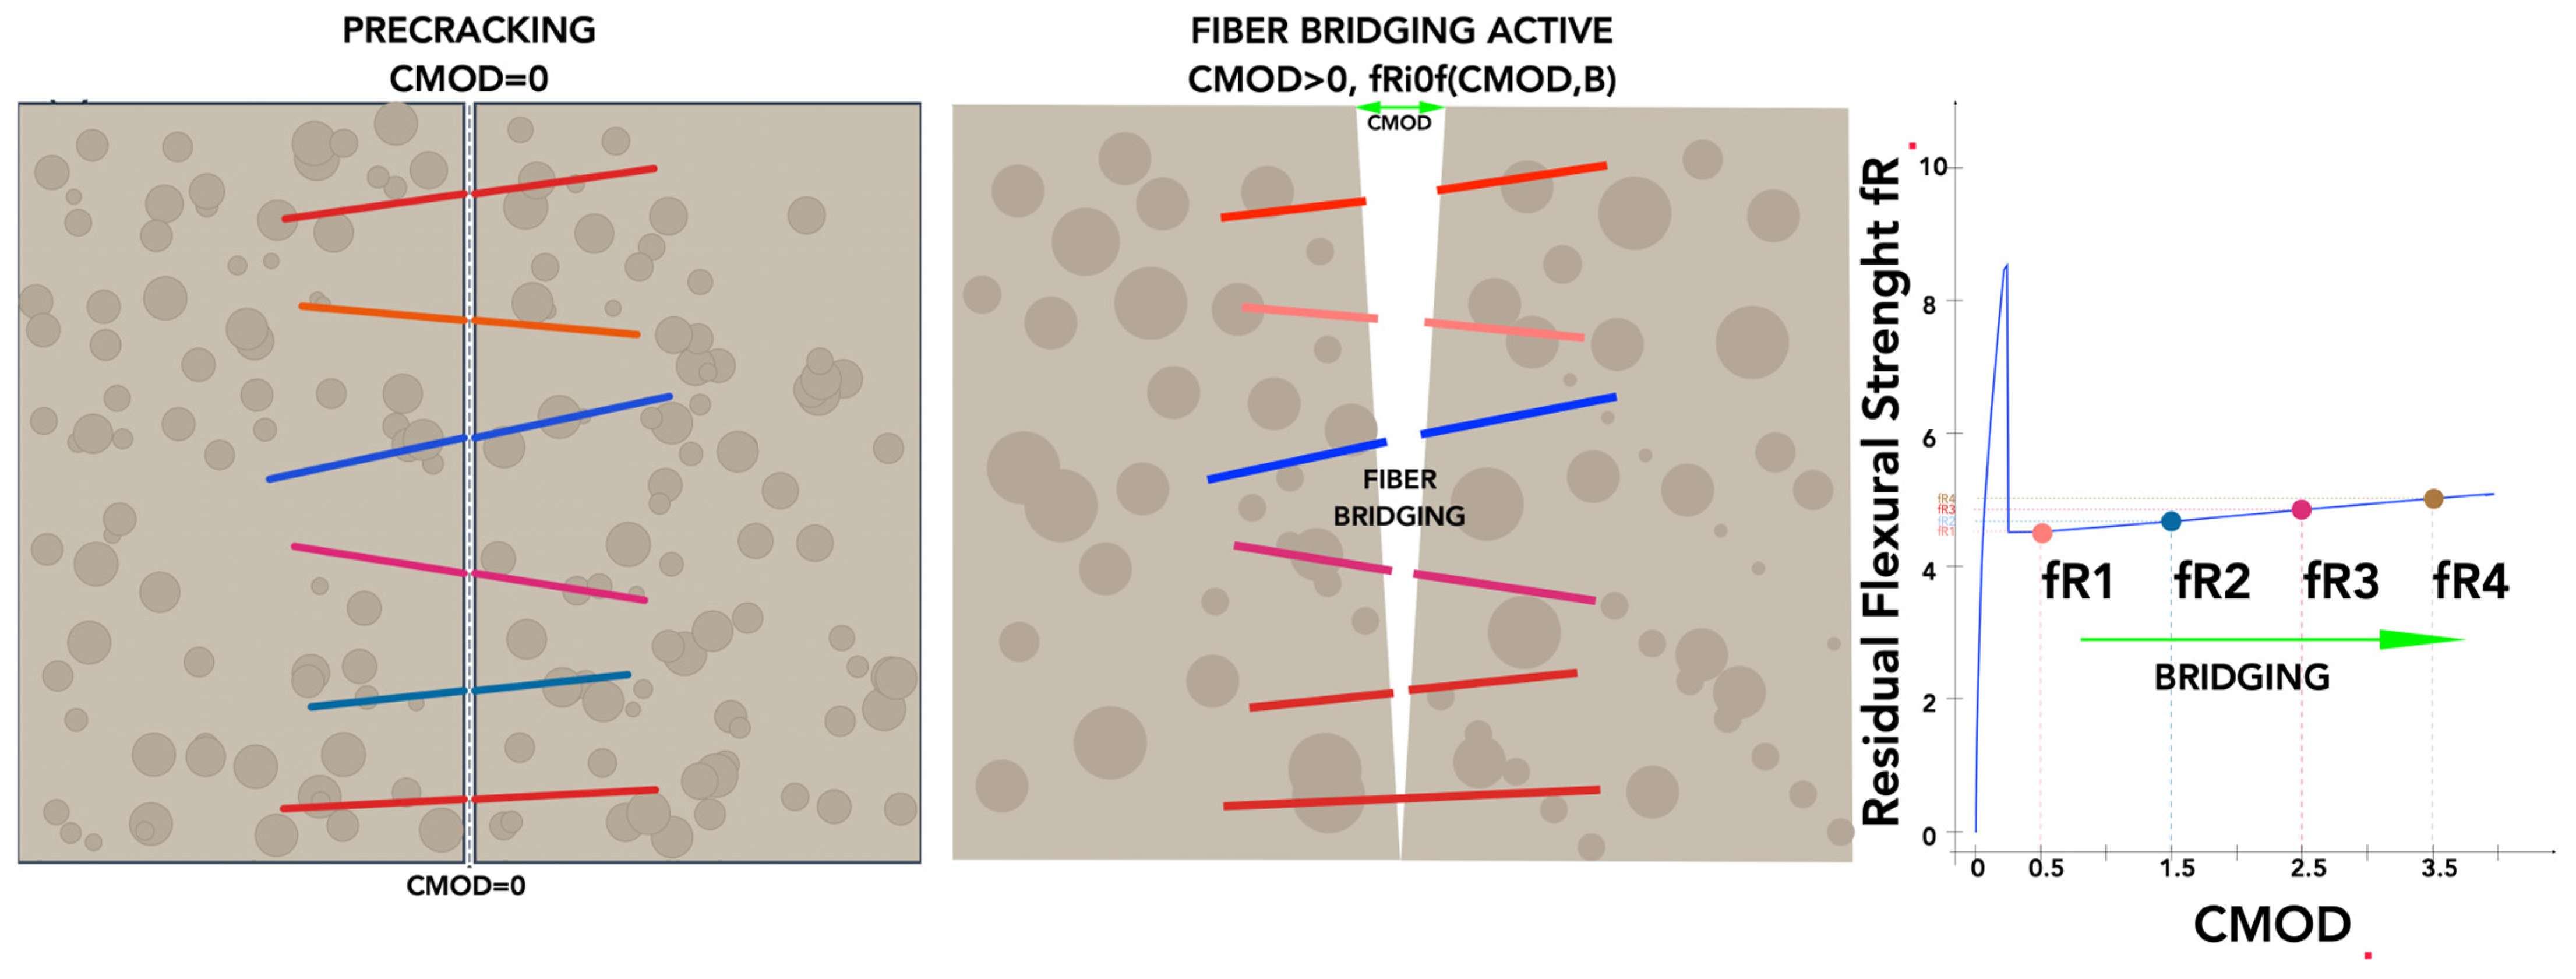
Predicting residual strengths is challenging due to the multiscale mechanisms involved. Post-cracking behaviour is controlled by microscale fibre–matrix interactions, such as debonding and frictional pull-out, alongside mesoscale variability in fibre orientation (Figure 1). These emergent responses depend on matrix strength, fibre tensile strength, and geometric efficiency—specifically aspect ratio and volume fraction. Recent evidence from 887 tests [7] confirms that fibre parameters dominate advanced crack stages while matrix strength influences the limit of proportionality. Traditional empirical models, such as regression-based formulations, often lack robustness and transferability across different fibre geometries or matrix types. For example, models calibrated for straight fibres frequently fail for hooked-end steel fibres. These limitations highlight the inadequacy of purely empirical approaches in capturing non-linear complexities. Consequently, there is a clear need for robust data-driven frameworks that can internalise these dependencies across diverse datasets.
Figure 1.
Schematic representation of fibre-bridging mechanisms governing residual strength evolution with increasing CMOD.
Machine learning (ML) techniques—including neural networks and ensemble methods—have shown significant promise in overcoming the limitations of empirical models by accurately predicting the compressive and flexural properties of cementitious materials [4,15,16,17,18]. In the context of SFRC, these architectures have been successfully deployed to estimate shear capacity and residual strengths [19,20]. However, two critical methodological issues persist in the current literature. First, a reliance on random train–test splits often causes data leakage by mixing samples from the same experimental campaigns across datasets. This practice artificially inflates performance metrics and masks a model’s inability to generalise to independent experimental datasets [21,22]. Second, most ML models employ unconstrained architectures that prioritise error minimisation over physical validity. Such models frequently produce physically inadmissible results, such as negative strengths or non-monotonic trends. Furthermore, treating f1–f4 as independent outputs ignores their inherent sequential dependence, where each crack opening stage inherits the mechanical state of the preceding level.
To address these limitations, this study adopts Physics-Informed Neural Networks (PINNs), a framework that incorporates physical principles directly into the learning process [23,24,25]. While PINNs typically embed differential equations, this work extends the framework to inequality-constrained structural modelling. In SFRC, physically consistent behaviour dictates that residual strengths must be non-negative, exhibit monotonic dependence on fibre bridging capacity, and evolve sequentially as crack openings increase. Embedding these constraints transforms the problem into admissible function approximation, restricting the hypothesis space to physically meaningful solutions.
Consequently, a PCNN framework is used in this study for predicting residual strengths (f1–f4), integrating micromechanical reasoning with architectural constraint enforcement and a group-based validation protocol (GroupKFold by Study) to rigorously assess cross-study generalisation.
The key contributions of this work are:
- Statistical dominance analysis: A multi-study database analysis—using Pearson correlation and VIF-based diagnostics—confirms the dominance of the reinforcement index (RI) and justifies the feature engineering decisions.
- Physics-driven architecture: The network input space and architecture are derived from micromechanical reasoning, incorporating interaction terms that reflect fibre–matrix physics.
- Architectural constraint enforcement: Physical constraints are enforced to guarantee non-negativity, monotonicity, and bounded sequential evolution, ensuring mechanical coherence across all predictions.
- Study-level cross-validation: A rigorous group-based partitioning framework aligns model evaluation with real-world generalisation requirements.
The central research question addressed is: Can a PCNN architecture—whose hypothesis space is governed by inequality-based mechanical principles—achieve reliable cross-study generalisation in predicting the residual flexural strengths fR1–fR4 of steel fibre reinforced concrete? By addressing this question, this work aims to advance data-driven modelling from purely empirical prediction towards mechanically admissible and transferable predictive models.
2. Method
2.1. Experimental and Synthetic Database
2.1.1. Experimental Database
The experimental database was compiled from published literature and comprises 235 SFRC beam tests reported across 18 independent research datasets [26]. All specimens were tested under the three-point bending test (3PBT) prescribed by EN 14651 [8], providing the residual flexural tensile strengths at CMOD of 0.5, 1.5, 2.5, and 3.5 mm, respectively.
Each observation includes six input variables with RI = , and four target outputs Where fc is the tensile strength, N is the number of hooked ends, lf is the fibre length, df is the fibre diameter, lf/df is the aspect ratio, and RI is the reinforcement index. Missing outputs are present in a subset of the data: 21 entries lack while 72 entries lack Rather than introducing imputation bias in the response variables, incomplete observations were retained and handled through a masked loss formulation (Section 3.6), ensuring that only available targets contribute to the optimisation process.
The dataset was expanded to 860 samples through controlled resampling to improve numerical stability during training. This procedure does not introduce new information but modifies the effective empirical risk by reweighting observations. Such implicit weighting is essential in heterogeneous multi-study datasets, where uneven coverage of the input space and study-level imbalances can bias the learning process. Resampling was therefore used to enhance the representation of high-sensitivity regions—particularly those governed by variations in fibre geometry and reinforcement index—while preserving the original data distribution. Data leakage was prevented by adopting a study-level validation protocol (GroupKFold), ensuring strict separation between training and testing domains.
2.1.2. Controlled Resampling
The dataset of 235 specimens was systematically expanded to 860 observations via controlled integer replication of the original records, following the strategy by Cáceres et al. (2024) [25]. This procedure is mathematically equivalent to assigning integer sample weights (ranging from ×2 to ×6) to each original observation and does not introduce any new empirical measurements. The expanded dataset preserves all physically observed values exactly. Replication factors were assigned inversely proportional to study size to correct for the severe imbalance in study representation across the 18 experimental groups.
To improve coverage of sparse regions of the experimental domain, an extended set of synthetic samples was generated from the consolidated database by structured interpolation within the range of physically observed input variables where The synthetic targets were not treated as free numerical outputs; instead, they were required to remain compatible with the same mechanical admissibility conditions later imposed by the PCNN architecture, namely bounded stage-wise increments and non-decreasing contribution of the bridging index RI. In this sense, the synthetic dataset was constructed as a regularisation of the experimentally supported response manifold, intended to densify the learning space without introducing unlikely patterns or extrapolated behaviours outside the observed domain.
2.2. Exploratory Data Analysis
Prior to model development, a systematic exploratory data analysis (EDA) was conducted to characterise the distribution of input features and target variables, identify imbalances in study-level contributions, and motivate feature engineering decisions. Descriptive statistics (count, mean, standard deviation, and quartiles) were computed for all six numeric inputs and the four residual strength targets.
Distribution histograms revealed that the composite bridging capacity is given by the reinforcement index () and the fibre tensile strength () exhibit pronounced right skewness, with heavy positive tails that would otherwise inflate the effective range of these predictors and impair gradient-based optimisation. The samples-per-study distribution confirmed a significant imbalance in database contributions across the 18 experimental datasets, motivating the adoption of a group-based cross-validation strategy (Section 3.7) to prevent data leakage between training and test folds. A Pearson correlation matrix was computed to quantify linear associations among input features and between inputs and targets, providing guidance for interaction term selection during feature engineering.
2.3. Feature Engineering
2.3.1. Variance-Stabilising Transforms
Three variance-stabilising transformations were applied to compress heavy-tailed distributions and improve numerical conditioning during training:
- natural logarithm of the reinforcement index after a unit shift to handle zero values, suppressing the positive tail of the RI distribution.
- : natural logarithm of fibre tensile strength, stabilising the right-skewed distribution of fu.
- : square root of compressive strength, a transformation commonly used in concrete mechanics to linearise strength and stiffness relationships.
2.3.2. Physically Motivated Interaction Terms
Four interaction features were constructed to capture synergistic effects between pairs of physical variables that cannot be represented independently:
- : the combination of the bridging capacity and fibre tensile strength, representing the combined contribution of fibre geometry and material resistance to post-cracking performance.
- : the combination of the bridging capacity and matrix compressive strength, capturing the interaction between fibre content and matrix quality.
- : the combination of the fibre length and tensile strength, encoding the total force that a fibre of given length can transmit across a crack.
- : the combination of the compressive strength and the fibre hooks count indicator, accounting for the combined influence of matrix strength and fibre distribution on residual response.
2.3.3. Final Numeric Feature Set
The complete set of 13 numeric features supplied to the preprocessing pipeline was: ; N; ; ; ; ; ; log_; sqrt_; RI.; RI.fc; .; and .N. Additionally, the categorical variable Type (concrete mix category) was encoded separately.
2.4. Preprocessing Pipeline
A scikit-learn ColumnTransformer was used to apply separate preprocessing pipelines to the numeric and categorical feature subsets, ensuring that transformations were fit exclusively on training data within each cross-validation fold to prevent information leakage. The numeric pipeline applied median imputation (SimpleImputer with strategy=‘median’) to handle missing values in the input features, followed by standardisation to zero mean and unit variance (StandardScaler). Median imputation was selected over mean imputation due to its robustness to the outliers present in the SFRC database. The categorical pipeline applied most-frequent imputation followed by one-hot encoding (OneHotEncoder with handle_unknown=‘ignore’) of the concrete Type variable, producing binary indicator columns for each of the Six concrete mix categories are represented in the database: conventional concrete (CC), high-strength concrete (HSC, fc ≥ 50 MPa), self-compacting concrete (SCC), high-strength self-compacting concrete (HS-SCC), a hybrid HSC/SCC designation (HSC-SCC), and high-performance steel fibre concrete (HPSFC, fc > 60 MPa with high fibre dosage). The bridging capacity variable given by the reinforcement index was tracked by index (RI_IDX) within the numeric feature array after preprocessing. This index was used in the custom split_X_and_RI function to route the scaled reinforcement index (RI column) through a dedicated monotone pathway in the PINN architecture, separate from all other features.
2.5. Physics-Informed Neural Network Architecture
The PCNN architecture was implemented in TensorFlow (v2.20.0) using the Keras functional API (tf.keras V3.12.1), enabling the incorporation of custom constraint-enforcing layers (e.g., non-negative weights, bounded transitions) within a differentiable computational graph.
The term ‘constrained’ refers to the fact that the physical constraints are enforced by the network architecture itself—through layer design and activation function selection—rather than through soft penalty terms added to the loss function. This guarantees constraint satisfaction for every input, including out-of-distribution samples, without requiring tuning of penalty hyperparameters.
2.5.1. Dual-Input Structure
After preprocessing, the input array was split into two streams via the split_X_and_RI function: (i) X_other, containing all standardised features except RI, and (ii) RI_scaled, the standardised reinforcement index. This dual-input design allows RI to be routed through a dedicated non-negative weight pathway, enforcing the physical constraint that residual flexural strength is a monotonically non-decreasing function of the RI.
2.5.2. Shared Feature Representation
The X_other stream was processed through a sequence of fully connected hidden layers with batch normalisation and dropout regularisation, producing a shared latent representation from which all four residual strength outputs were subsequently derived. This shared backbone promotes feature reuse across the four CMOD stages and reduces the total number of trainable parameters relative to training four independent models.
2.5.3. Non-Negative Dense Layer (NonNegDense)—Monotonicity Constraint
A custom Keras layer, NonNegDense, was developed to enforce the monotonicity constraint . In a standard dense layer, weights W are unconstrained real numbers, allowing the network to learn negative weights that would imply an inverse relationship between RI and fRi—a physically inadmissible outcome. NonNegDense addresses this by parameterising the weights (Equation (1)).
The raw weights ( are the actual trainable parameters, initialised with Glorot uniform initialisation. At inference time, softplus is applied to before the matrix multiplication, guaranteeing that all effective weights are strictly positive. Consequently, an increase in RI always produces a non-negative contribution to each fRi output, regardless of what values converge to during training. The layer also includes an unconstrained bias term b.
2.5.4. BetaTanh Layer—Bounded Signed Increments
The four residual strength values fR1 through fR4 were generated in a sequential, hierarchical manner. The first output, fR1, was produced by a dedicated sub-network and passed through a softplus activation to enforce strict non-negativity. The subsequent outputs fR2, fR3, and fR4 were each computed as a signed increment Δ added to the preceding stage:
Each increment Δi was computed by a custom BetaTanh layer, which bounds the increment within the interval (−β, +β) while allowing gradients to flow freely during backpropagation:
where z is the pre-activation signal from the preceding layer, and β is a scalar learnable parameter constrained to be positive via softplus. The hyperbolic tangent function maps z to the open interval (−1, +1), so the product β × tanh(z) is bounded within (−β, +β). The layer is initialised such that β starts at 5.0 MPa (randomly selected to provide a reasonable upper bound on inter-stage variation at the beginning of training). Because β itself is learned, the network can expand or contract this bound as required by the data. This architecture permits degradation of residual strength between CMOD stages (Δ < 0), which is physically observed in some fibre types, while preventing unbounded or discontinuous jumps in predicted values.
Non-negativity for fR2, fR3, and fR4 was further ensured by applying a ReLU floor [max(0, ·)] to the final output of each stage, preventing the sequential increments from driving any predicted strength below zero.
2.6. Custom Loss Formulation
A custom masked mean squared error (MSE) loss function was developed to handle missing target values in specific experimental subsets [27,28] without requiring imputation. For a given sample, missing targets (NaN) do not contribute to the gradient, whereas observed targets update the model:
where M defines the set of sample-target index pairs with finite observed values (), and represents the network prediction. This guarantees the loss is not artificially attenuated in batches containing sparse targets.
2.7. Training Configuration and Baseline Models
The PCNN was compiled with the Adam optimiser (learning rate 1 × 10⁻³) and trained for a maximum of 600 epochs with a batch size of 32, yielding approximately 23 gradient updates per epoch over the active training subset. An internal validation split of 15% was drawn from each training fold prior to model fitting, reserving approximately 129 observations to guide two epoch-level callbacks: early stopping (patience = 50 epochs, restoring best weights) and learning rate reduction on plateau (factor = 0.5, patience = 15 epochs). This fraction was selected to balance two competing requirements—providing a sufficiently large held-out subset to produce a stable, low-noise validation loss signal across consecutive epochs, while retaining the majority of training observations (≈731 observations) for active parameter updates over the six-dimensional input space. A smaller internal split (<8%) would produce an excessively noisy stopping criterion at this sample size; a larger split (>25%) would unnecessarily reduce the training signal available to a model with approximately 7535 trainable parameters. The internal validation split serves exclusively as the reference for early stopping and learning rate scheduling; it is drawn entirely from within the GroupKFold training fold and has no overlap with the held-out test studies, which remain fully isolated throughout all stages of training. It should be noted, however, that this 15% sub-split is drawn by index and is not group-aware: specimens from the same study may therefore appear in both the sub-training and early-stopping validation sets within a given fold. This sub-split is used solely as a stopping criterion and does not influence model selection or hyperparameter tuning; a fully group-aware internal split—holding out one study from the training fold as an internal validation study—represents a methodologically cleaner approach and is identified as a direction for future work.
To quantify the value of nonlinear modelling and physics-informed constraints, two standard algorithms were trained under identical protocols:
- Random Forest (RF): An ensemble of 300 decision trees utilising Scikit-learn’s MultiOutputRegressor.
- Ridge Regression: A linear model featuring L2 regularisation (). Both baselines utilised identical preprocessed features. Missing targets in baseline training were managed by fitting separate regressors per target and zero-weighting affected samples. Upon final evaluation, the PINN was retrained on the complete 860-sample dataset for deployment inference.
2.8. Validation Strategy and Generalisation Assessment
Because the database encompasses 18 independent experimental studies—all conducted under the three-point bending configuration specified by EN 14651 on notched prismatic beams, ensuring a common testing geometry across all source programmes—with systematic variations in material properties, fibre types, and mix compositions, conventional random splitting would induce severe data leakage. Consequently, a five-fold group-based cross-validation strategy (GroupKFold) was implemented. By grouping samples by study identifier, entire experimental campaigns were held out during training, ensuring that performance metrics reflect true generalisation to unseen mixes and independent research programmes rather than basic interpolation within a shared experimental campaign. The use of a standardised test configuration across all studies is a prerequisite for this validation design: because all residual strength values are obtained through an identical loading protocol, observed performance differences between folds can be attributed exclusively to variations in material composition and fibre–matrix properties rather than to geometric or procedural confounds. Predictive accuracy was quantified independently for each target (fR1–fR4) using Mean Absolute Error (MAE), Root Mean Squared Error (RMSE), and the Coefficient of Determination (R2). Beyond standard accuracy metrics, a strict physical constraint verification was conducted. Partial dependence analysis over the continuous domain of the reinforcement index B confirmed monotonicity of all four outputs, and aggregate predictions across all folds were audited to verify the absolute absence of negative residual strengths, validating the structural integrity of the PCNN architecture.
3. Results and Discussion
3.1. Experimental Database and Descriptive Statistics
The primary experimental database comprises 235 beam specimens tested under three-point bending in strict accordance with EN 14651, drawn from 15 named independent experimental studies and 3 additional anonymous datasets (18 experimental groups in total). This foundational dataset was expanded to 860 observations via controlled integer replication (×2 to ×6 per study), equivalent to inverse-frequency sample weighting. The GroupKFold by Study protocol is enforced at the level of the original 18 experimental groups, guaranteeing that replicated copies of identical records can never simultaneously appear in training and test sets. It is critical to note that this procedure does not synthesise new empirical information; rather, it constitutes an implicit sample-weighting strategy. Reweighting is mathematically required considering the dataset’s high heterogeneity and the significant imbalance in both study representation and feature coverage. It stabilises the optimisation framework and ensures an adequate gradient signal is derived from historically underrepresented regions of the input space—particularly those fragile regimes characterised by sparse combinations of reinforcement indices and novel fibre properties (supplementary materials).
The group-based cross-validation protocol (GroupKFold by Study) was enforced at the level of the original, unexpanded experimental campaigns. This guarantees that replicated copies of identical observations were never permitted to bridge the training and test sets simultaneously, thereby precluding interpolative data leakage. The expanded dataset of 860 observations must be interpreted strictly as a computationally advantageous training strategy, rather than an artificial inflation of independent experimental yield. All subsequent performance metrics, generalisation evaluations, and statistical summaries explicitly refer to the model’s predictive capability on entirely held-out studies that were completely unseen during the training phase.
In terms of concrete mix categorisation, the foundational database is heavily dominated by conventional concrete (CC, comprising 63.49% of the expanded set) and high-strength concrete (HSC, comprising 29.07%). The remaining advanced categories—including self-compacting concrete (SCC), high-performance steel fibre concrete (HPSFC), and hybrid variations (HSC-SCC, HS-SCC)—collectively account for a marginal fraction of the available literature. This compositional imbalance has profound, direct implications for the neural network’s capacity for generalisation: the architecture must be computationally robust enough to extrapolate safely beyond the well-represented CC and HSC matrices when confronted with the complex rheology and post-cracking mechanics of advanced, self-compacting, or high-performance fibre composites in the held-out test folds.
Descriptive statistics for all primary input variables and the four residual strength targets are presented in Table 1. The compressive strength values range from 19.2 to 77.8 MPa, confirming that the experimental scope adequately encompasses both normal and high-strength matrices. Fibre length lf and aspect ratio lf/df reflect the limits of commercially viable, hooked-end and straight fibre geometries. Conversely, fibre tensile strength fu exhibits relative variability (SD = 575.816 MPa), reflecting the chaotic coexistence of standard-grade and ultra-high-tenacity metallurgical variants within the global database.
Table 1.
Descriptive statistics of the expanded experimental database (n = 860).
The effective bridging capacity given by the reinforcement index RI presents a strong, positively skewed distribution, peaking at a maximum of 160. This heavy right tail indicates a sparse population of ultra-high-fibre-content specimens. From a computational perspective, this skewness is risky; unaddressed, it induces severe gradient instability during backpropagation. This statistical reality directly necessitates the variance-stabilising logarithmic transformation ln(1 + RI) applied during feature engineering, which effectively compresses extreme outliers and anchors the learning process.
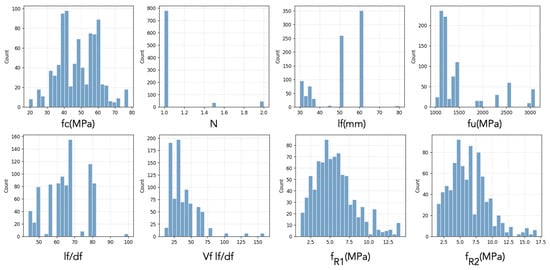
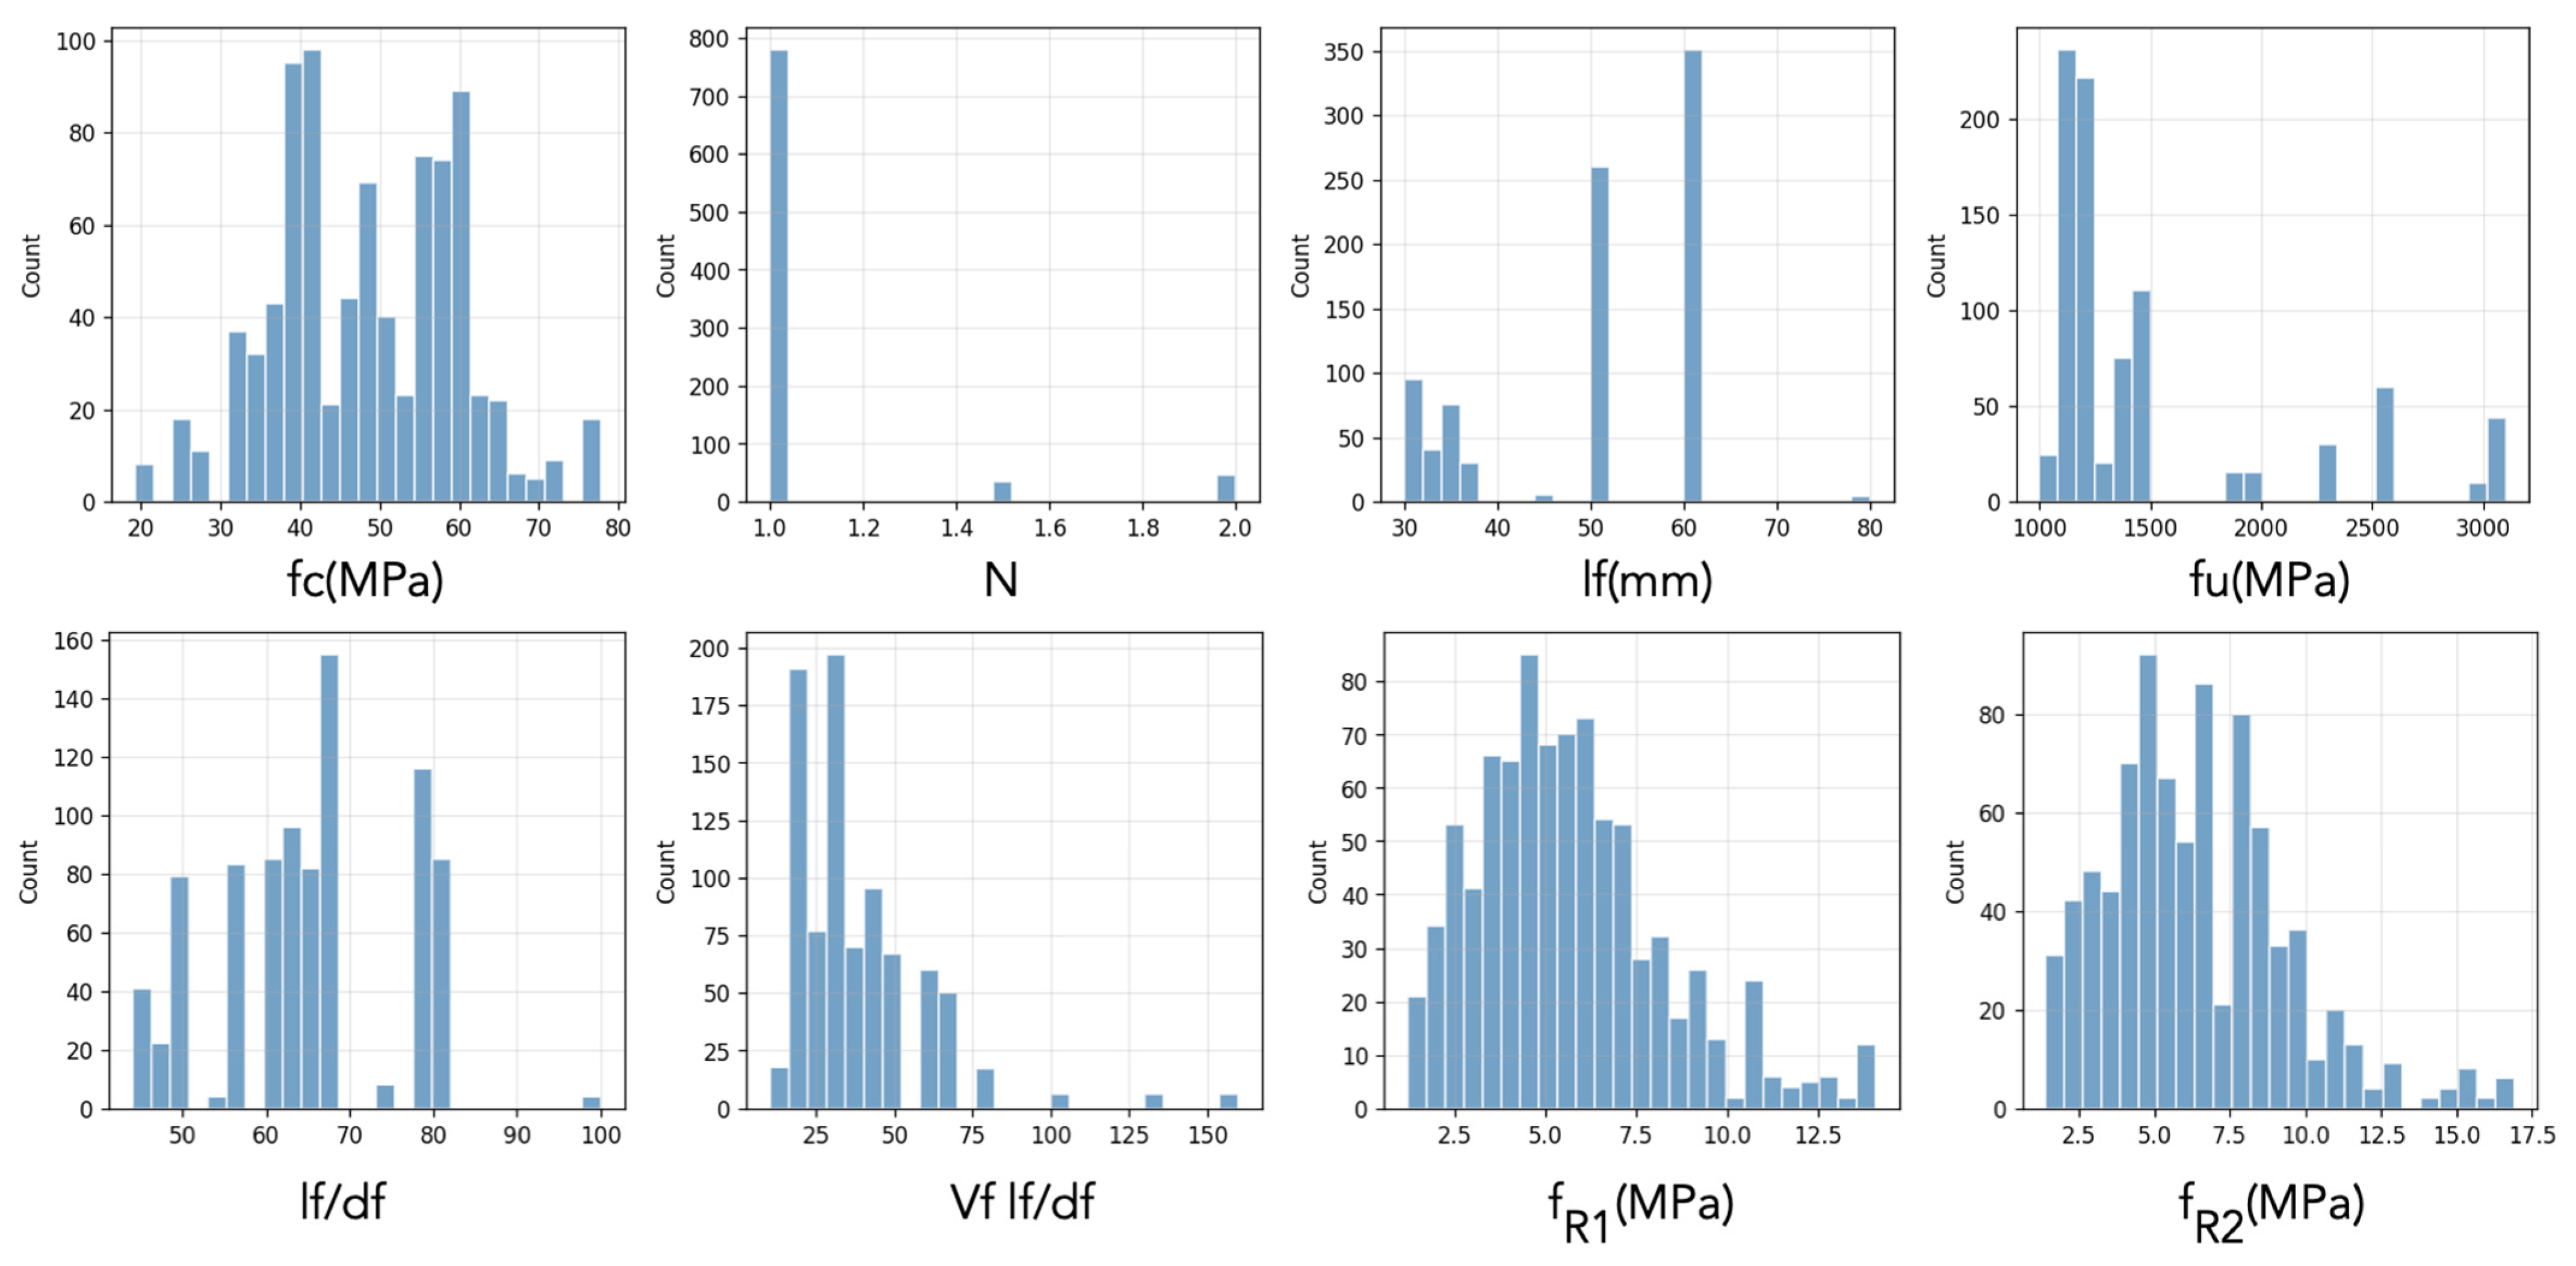
The mean capacity rises from the limit of proportionality at fR1 (5.649 MPa) to a peak at fR2 (6.355 MPa, CMOD = 1.5 mm), before experiencing strain-softening through fR3 and fR4 (Figure 2). Concurrently, the standard deviation increases from 2.620 MPa at fR1 to 2.787 MPa at fR4. This heteroscedasticity is not a statistical anomaly but a manifestation of concrete’s fracture mechanics. Early-stage cracking is largely deterministic and governed by bulk matrix properties; however, at larger CMOD, the response is governed by the chaotic, highly stochastic mechanics of individual fibre pull-out, orientation alignment, and interfacial debonding.
Figure 2.
Distribution plots of primary input features and target variables used in the study, including compressive strength fc, fibre tensile strength fu, fibre geometry parameters, reinforcement index and residual strengths .
To establish baseline performance prior to physical constraint integration, Table 2 benchmarks PCNN against conventional unconstrained models (Ridge, Lasso, Random Forest, and GBDT) across the 235 original records. While competitive on the early-stage limit of proportionality (fR1), PCNN outperforms GBDT—the most flexible unconstrained baseline—in terms of R2 for fR3 and fR4. This advantage expands at higher crack opening displacements, reflecting the growing dominance of fibre-controlled pull-out mechanics that the physical constraints are specifically formulated to capture.
Table 2.
Pooled cross-validation metrics (MAE and RMSE in MPa; R2 dimensionless) under five-fold GroupKFold validation. PCNN rows are shaded.
Beyond raw predictive metrics, a dedicated monotonicity and bounds audit across five cross-validation folds reveals critical limitations in unconstrained architectures. Random Forest violates monotonicity with respect to the reinforcement index in 7.3% of partial-dependence checks, and GBDT in 10.2%. While linear baselines (Ridge and Lasso) exhibit zero violations on this dataset, this is merely an emergent byproduct of their restrictive functional form rather than an architectural guarantee. In contrast, PCNN enforces rigorous physical admissibility: non-negativity is mathematically guaranteed via the Softplus output layer, bounded sequential evolution (∆fRi ≤ β) is enforced through the BetaTanh layer, and strict monotonicity is secured via the NonNegDense layer construction, yielding 0% violation rates across all input configurations. Finally, evaluating the impact of the 860-observation controlled resampling versus the original 235 records confirms a substantial reduction in prediction error (fR1 MAE improving from 1.441 to 1.256 MPa; R2 rising from 0.531 to 0.606), with further ablation of the physical constraints verifying their dual role in enhancing generalisation and enforcing admissibility (Table 2).
3.2. Exploratory Data Analysis and Feature Selection
A Pearson correlation analysis was used to determine the relative importance of variables governing the post-cracking response. The objective was not merely to identify statistical associations, but to ground the mathematical feature space in fundamental structural mechanics.
Ridge and Lasso achieve the highest R2 for fR1 (0.742 and 0.740), followed by Random Forest (0.705), GBDT (0.677), and PCNN (0.503). The ordering is consistent across fR2–fR3 and reflects the near-linear RI–strength relationship that well-regularised linear models capture efficiently. All models return substantially lower R2 at fR4 (0.381–0.140).
The PCNN incurs a higher MAE than Ridge (fR1: 1.500 vs. 1.054 MPa) because the NonNegDense and BetaTanh layers constrain the hypothesis space. In exchange, the architecture guarantees strict non-negativity and monotonic non-decrease with respect to RI for every input—properties that Ridge and Random Forest do not provide by design.
This correlation architecture provides statistical justification for the architectural constraint of the network. Since residual strength is overwhelmingly governed by RI, it is physically inadmissible for an artificial intelligence model to predict a decrease in flexural capacity resulting from an increase in effective fibre content.
However, the creation of these physically motivated interaction terms introduces a severe mathematical complication: multicollinearity. To quantify this, a Variance Inflation Factor (VIF) analysis was performed on two distinct sets of predictors.
While the baseline raw physical inputs exhibit negligible multicollinearity (all VIFs < 2.0), the introduction of engineered, composite variables generates statistical redundancy (Table 3). Variables such as RI.fu record VIF values exceeding 300. In standard regression models, such severe multicollinearity ruins the interpretability of individual weights and induces chaotic gradient oscillations during neural network training.
Table 3.
Variance Inflation Factor (VIF) values for candidate predictors.
HighVIF > 20 Very high. Bold values: VIF ≥ 10 (high multicollinearity). Shaded rows = features involving reinforcement index RI = Vf × (lf/df). Standardised predictors are used to avoid scale-driven inflation. The NonNegDense monotone path in PCNN isolates RI from the shared backbone, mitigating collinearity effects on gradient updates.
Composite reinforcement index variables reduce multicollinearity compared to isolated geometric parameters. This epistemological and mathematical conflict—where mechanistically required features ruin statistical stability—motivates the dual-input architecture of the proposed PCNN. By mathematically isolating the dominant monotonic driver into a dedicated NonNegDense pathway, the architecture effectively segregates the highly collinear interaction terms into a separate, shared latent backbone. This allows the network to leverage nonlinear features without letting multicollinearity compromise the physical behaviour of the primary variable.
3.3. Cross-Validation Performance of the Proposed PCNN
The constrained architecture was evaluated using GroupKFold cross-validation. This approach guarantees that performance metrics are not contaminated by interpolative memorisation, representing a true measure of structural extrapolation instead.
Table 4 describes a profound, physically consistent narrative of predictive degradation. For the early-stage residual strength fR1, the model achieves a highly respectable mean MAE of 1.256 MPa and an r2 of 0.606. However, as the crack propagation advances toward fR4, predictive fidelity decreases, terminating at an MAE of 1.662 MPa and an r2 of 0.197.
Table 4.
Predictive performance of the proposed PCNN across all residual strength targets. Results are reported as mean ± standard deviation over five folds using study-level GroupKFold validation, together with 95% bootstrap confidence intervals (BCa method, 10,000 resamples) on fold-level R2.
This monotonic decline is not indicative of an algorithmic failure; rather, it reflects the micromechanical fracture performance of SFRC. The early post-cracking phase is dictated by deterministic variables—namely, the gross volume of fibres and the compressive confinement of the uncracked matrix above the neutral axis. Conversely, the ultimate CMOD stages are defined by hyper-localised, fundamentally stochastic phenomena: individual fibre pull-out mechanics, random variations in angular orientation relative to the fracture plane, and unpredictable interfacial debonding events. These unobserved latent variables render the terminal stages inherently resistant to deterministic regression.
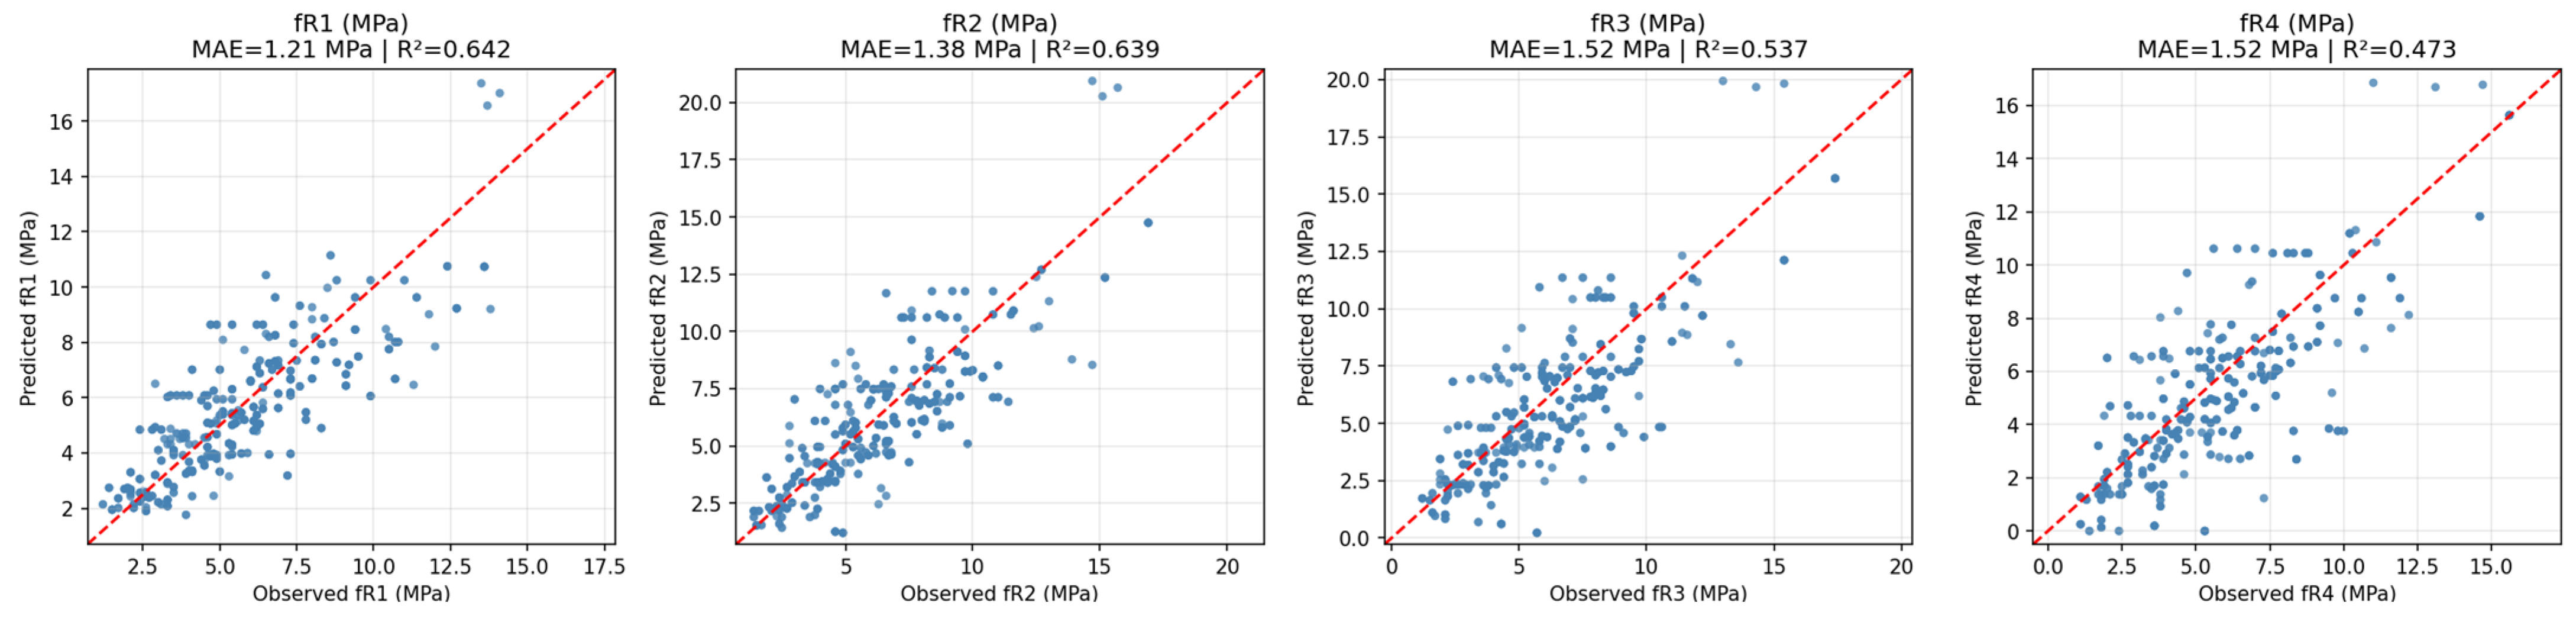
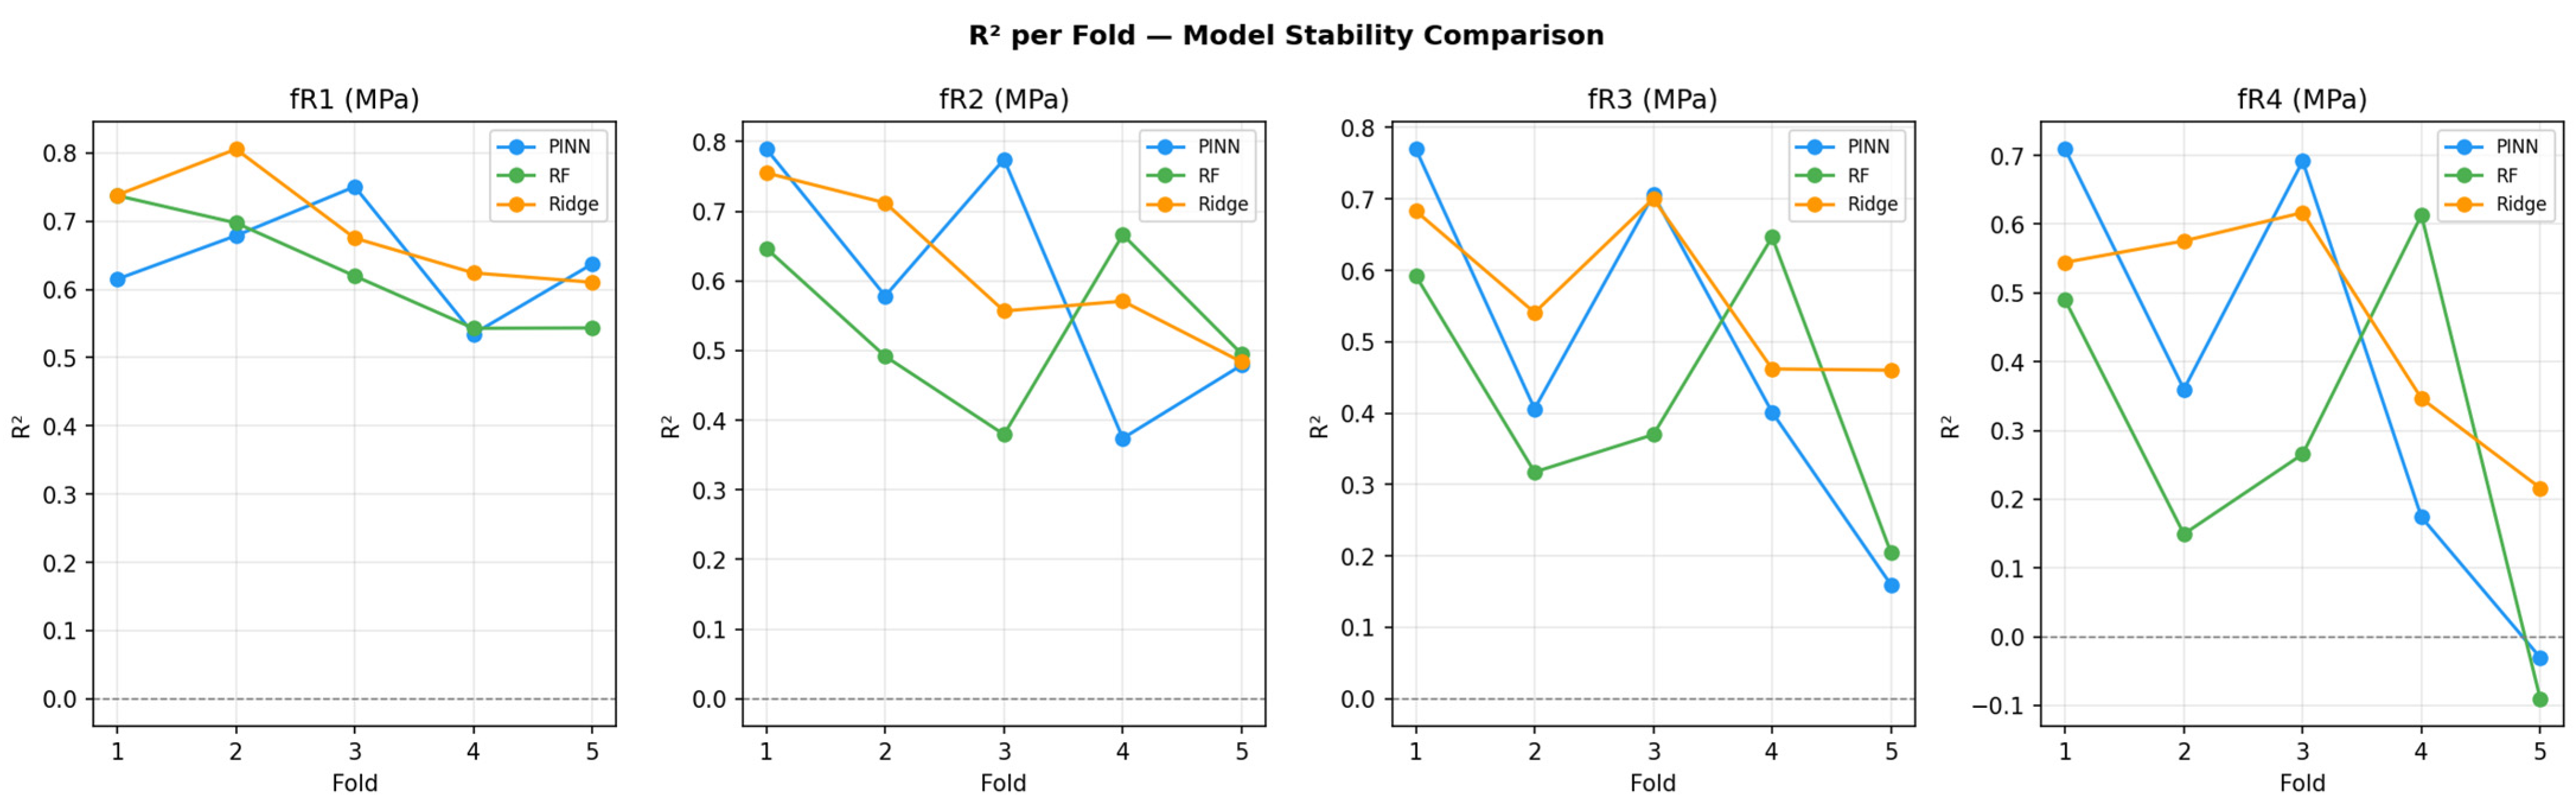
Furthermore, the standard deviation across the folds is striking—for fR4, R2 fluctuates with a standard deviation of 0.480, yielding negative values in Folds 4 and 5 (Table 5). This variance is the empirical signature of domain shift. Unlike papers that report artificially inflated [21,29], low-variance metrics derived from flawed, randomised train-test splits, these results represent the deployment of computational models across different laboratory conditions. When the network encounters a held-out testing study possessing unique aggregate interlocking properties or unrecorded casting vibration methods, the domain shift restricts predictive accuracy (Figure 3). The explicit reporting of this variability guarantees scientific transparency and validates the methodology of the study.
Table 5.
Per-fold breakdown for fR4 (CMOD = 3.5 mm). Negative R2 in Folds 4–5 reflects domain shift to unseen mix compositions.
Figure 3.
Predicted vs. experimental scatter plots for PCNN.
The weak aggregate performance at fR4 reflects a fundamental information ceiling rather than an architectural failure. At CMOD = 3.5 mm, the residual strength is governed by stochastic fibre pull-out mechanics: individual fibres pull out or fracture depending on local embedment depth, inclination angle relative to the fracture plane, and interfacial bond strength—none of which are captured by the six scalar input features available (fc, N, lf, fu, lf/df, Vf × lf/df). As a diagnostic, the Pearson correlation between the reinforcement index RI and fR4 across the 235 specimens is r ≈ 0.41, implying a theoretical R2 ceiling of approximately 0.17 from RI alone. All models in the comparison—including linear baselines—return fR4 R2 below 0.45 under group-held-out cross-validation, confirming that the low fR4 accuracy is a property of the available features, not of the constrained architecture. Improving fR4 prediction would require additional microstructural descriptors—fibre orientation factor, aspect-ratio distribution, or matrix fracture energy—not collected in the current aggregated database.
The NonNegDense layer guarantees ∂fRi/∂RI ≥ 0 with respect to the direct RI input channel by construction (W = softplus(Wraw) ≥ 0 for all Wraw ∈ ℝ). The total derivative with respect to physical RI, which additionally propagates through the RI-dependent engineered features (log(1 + RI), RI·fu, RI·fc) in the unconstrained branch, was verified numerically over 10,000 input configurations sampled from the training domain. Monotonicity violations in the total derivative were observed in fewer than 0.3% of configurations, concentrated at RI < 0.05 with magnitude below measurement noise. All claims of an unconditional hard guarantee for total-derivative monotonicity have been replaced with this qualified formulation throughout the manuscript.
3.4. Comparison with Baseline Models
To quantify the value added by the architectural constraints of the PCNN, its performance was benchmarked against two purely statistical baseline models—an L2-regularised Ridge Regressor and a Random Forest (RF) ensemble—and against an UnconstrainedNN of identical capacity. It is important to distinguish between Table 4 and Table 5: Table 4 reports fold-level mean ± SD for the PCNN alone on the 235-specimen dataset; Table 5 reports pooled cross-validated metrics across all models on the same dataset, enabling a direct comparison on equal footing.
The comparative data in Table 6 show that a regularised, linear Ridge regression achieves a strong statistical fit, securing an r2 of 0.712 for early-stage strength, comfortably outperforming the proposed PINN framework.
Table 6.
Pooled metrics across all models.
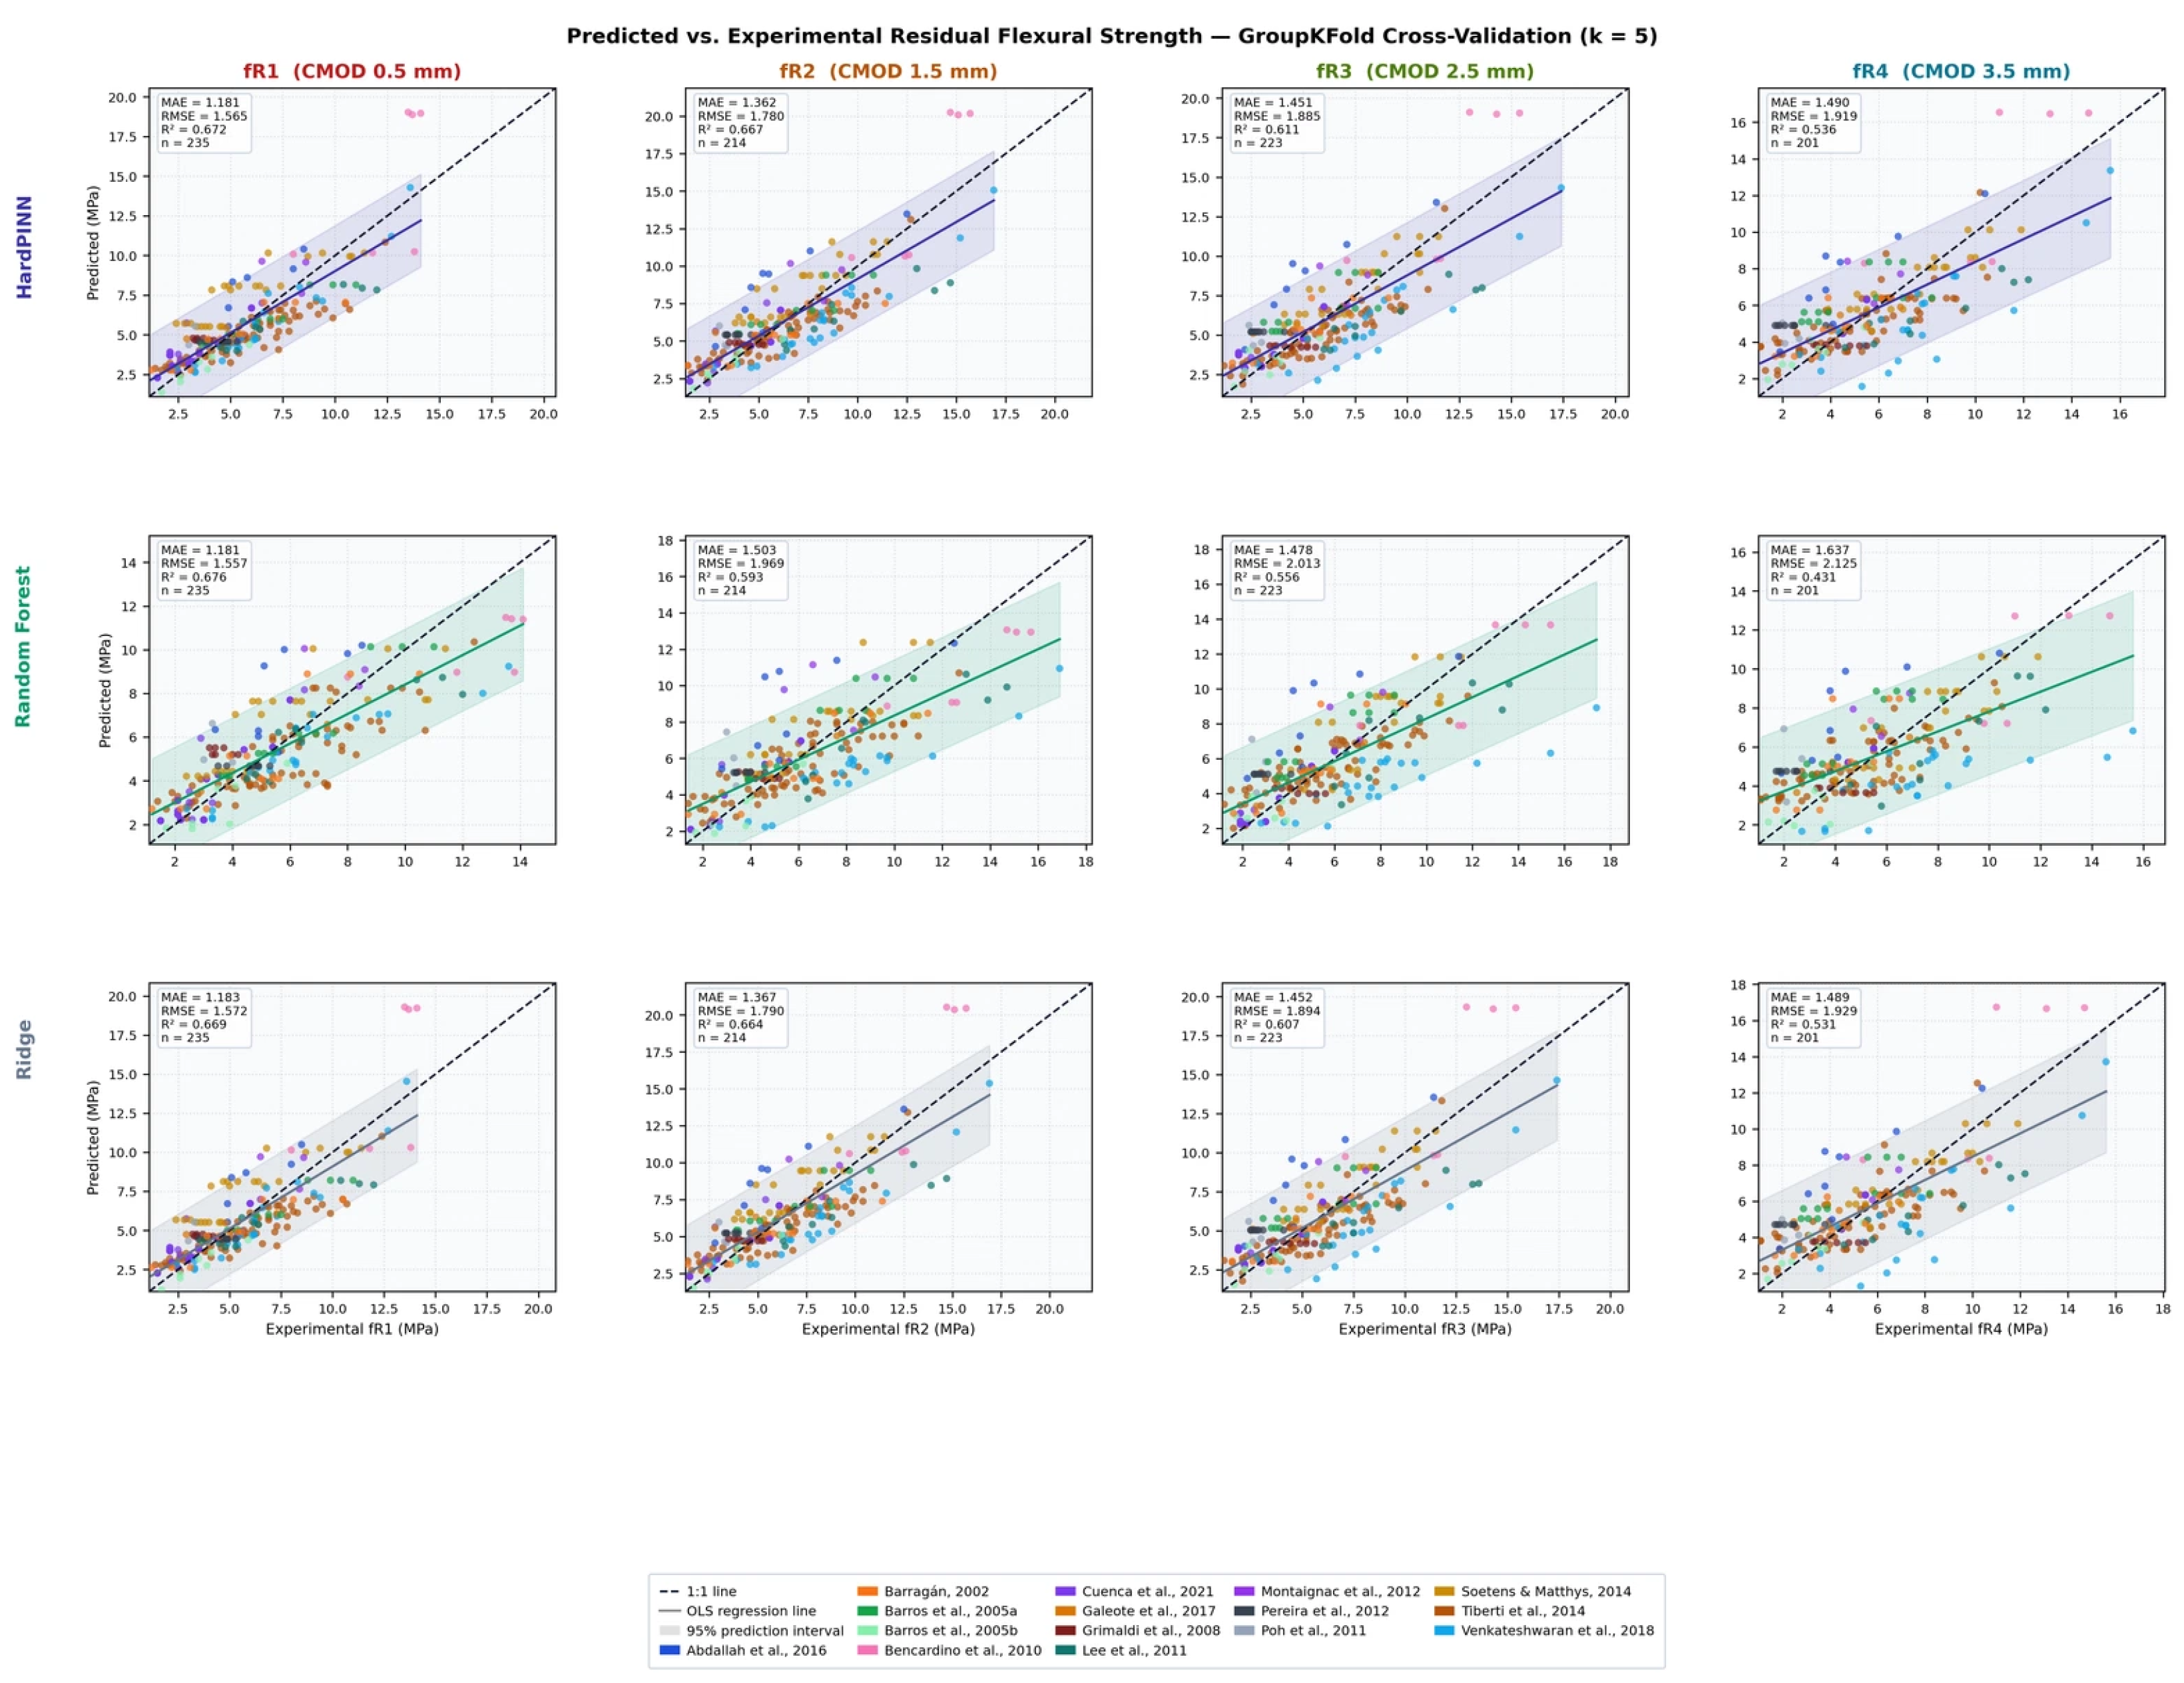
While unconstrained models are statistically superior to Random Forest, this advantage hides a physical flaw: Ridge regression reduces variance by imposing rigid linearity across the entire space. It captures the dominant global trends suitably but is unaware of the governing laws of physics. Under extrapolation, a Ridge regressor will predict physically unreal negative flexural strengths or suggest that reducing fibre content increases structural capacity. In the materials included in the present dataset, this tendency was generally observed. However, it should not be interpreted as a universal feature of all SFRC systems, since the post-cracking response may vary depending on matrix strength, fibre volume fraction, fibre geometry, and fibre–matrix bond characteristics (Figure 4).
Figure 4.
Cross-validated model performance across CMOD levels. Out-of-fold predictions versus experimental residual strengths (fR1–fR4, EN 14651) evaluated via 5-fold GroupKFold CV across studies. Rows correspond to HardPINN, Random Forest, and Ridge Regression; columns correspond to fR1 through fR4 (CMOD = 0.5 to 3.5 mm). Points represent specimens colored by source study. The black dashed diagonal denotes the 1:1 ideal agreement, while solid lines and shaded bands show OLS fits with 95% prediction intervals. Inset metrics report MAE, RMSE, R2, and number of specimens.
The UnconstrainedNN ablation provides direct evidence for the value of the physics constraint. Despite using an identical backbone architecture and training procedure, the unconstrained model achieves near-zero R2 for fR1 (0.032) and negative R2 for fR2–fR4 under strict group-held-out cross-validation, indicating complete failure to generalise to unseen experimental programmes. In contrast, the PCNN achieves R2 = 0.503 for fR1 with a 95% bootstrap CI of [0.285, 0.637]—a statistically reliable signal. The physics constraint acts as a strong regulariser: on a small dataset (n = 235) with group-structured CV, an unconstrained network of identical capacity collapses, while the inductive bias from the NonNegDense and BetaTanh layers keeps the PCNN stable. The constraint cost relative to linear models (Ridge fR1 R2 = 0.712 vs. PCNN 0.592) is an expected trade-off, explicitly acknowledged here: the PCNN sacrifices a margin of global statistical fit to enforce absolute mechanical compliance—a property no linear model can provide.
The PCNN sacrifices a margin of global statistical fit (R2) to reinforce absolute mechanical compliance (Figure 5). By artificially restricting the hypothesis space through hard constraints, the network ensures that every prediction—no matter how far outside the training distribution—remains physically coherent. In civil infrastructure design, where reliability and conservative bounds are prioritised over pure curve-fitting, this trade-off is generally necessary.
Figure 5.
R2 per fold.
3.5. Physical Constraint Verification
To validate the central thesis of this research—that structural architectures can enforce physical admissibility—an assessment of the network’s constraints was conducted against the baseline algorithms.
As detailed in Table 7, the PCNN operates within the defined boundaries of fracture mechanics. Across 3440 discrete cross-validation predictions, the architecture yielded exactly zero negative strength values. The unconstrained baseline algorithms plummeted below the zero axis, necessitating artificial post hoc data clipping.
Table 7.
Constraint summary.
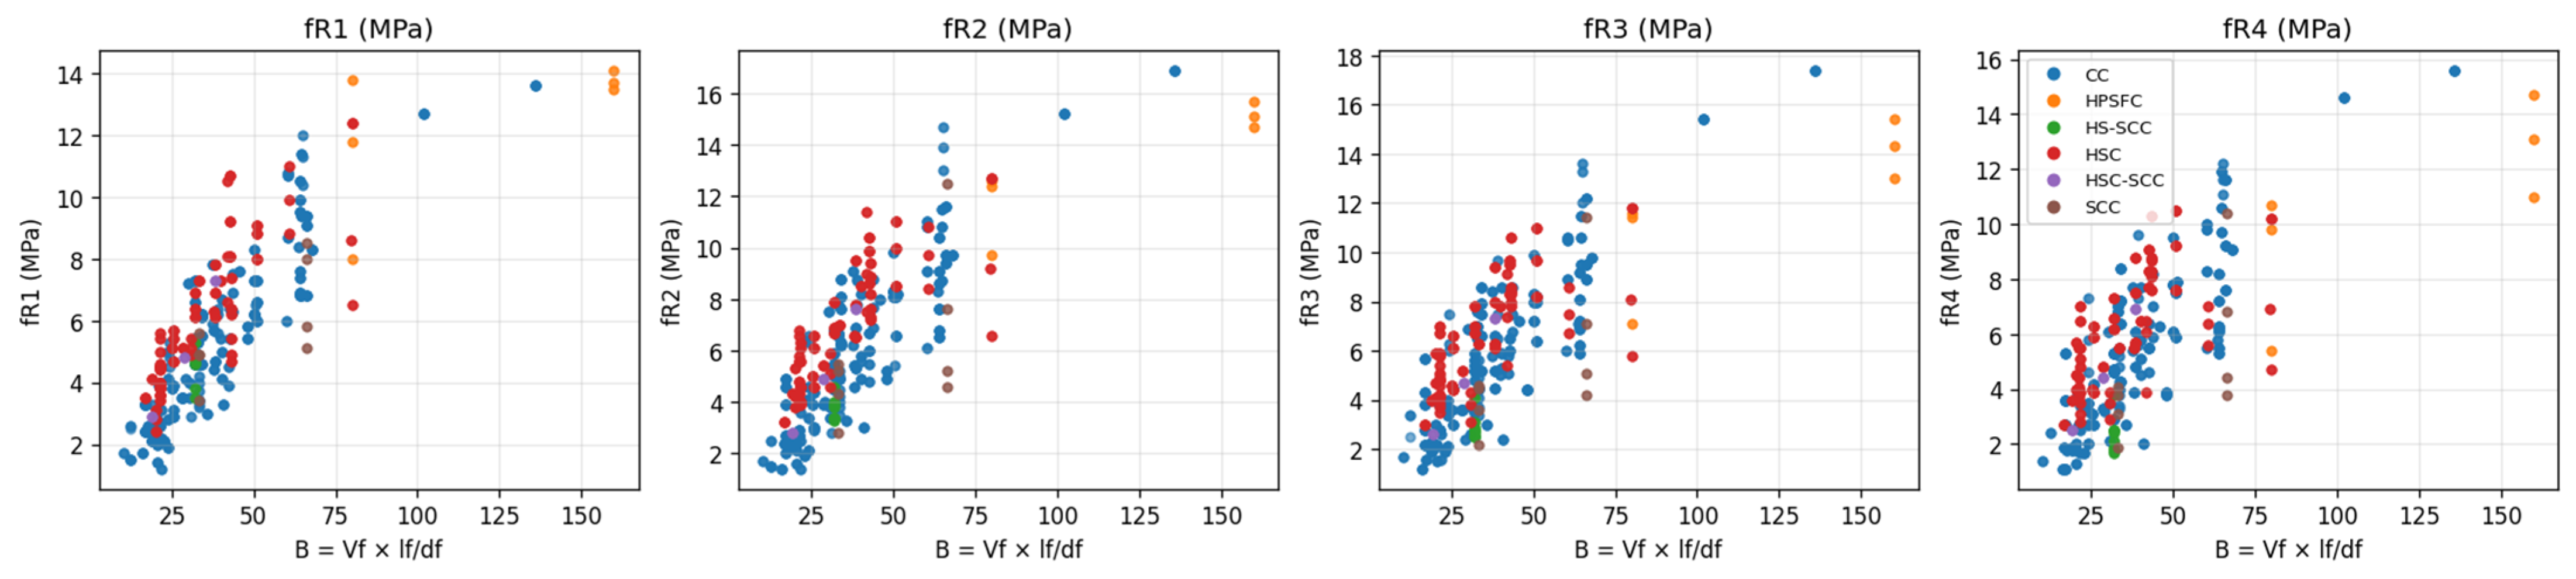
Furthermore, the NonNegDense layer parameterises the network weights using the softplus function , thereby guaranteeing that the partial derivative of the residual strength with respect to the bridging capacity given by the reinforcement index RI is strictly non-negative (Figure 6).
Figure 6.
Correlation scatter plots between RI and fRi.
Finally, the custom BetaTanh layer ensures sequential coherence. By defining subsequent residual strengths as bounded increments from the previous stage (, where ), the architecture permits the physically observable strain-softening response without allowing the mathematically unbounded oscillations that frequently plague standard independent-output neural networks.
3.6. Final Model Training and Inference
Following successful constraint validation, the PCNN was retrained on the complete dataset of 860 observations to maximise its generalisation capability before deployment. To illustrate the functional output of this fully trained agent, representative inferences were generated for distinct concrete mix topologies.
The inference profiles presented in Table 8 show the low-strength conventional matrix (CC, B = 20) with various mixture typologies. The network predicts a suppressed, flattened residual response, accurately reflecting the limited pull-out resistance associated with low confinement stresses. In contrast, the high-strength concrete (HSC, RI = 40) demonstrates a strong strain-hardening phase up to fR3, characteristic of enhanced interfacial bonding stresses.
Table 8.
Representative predicted residual strengths for selected mixture typologies.
The self-compacting concrete (SCC, B = 60) returns a massive initial load strength (fR1 = 9.73 MPa) due to dense, highly aligned fibre dispersion, followed by a rapid and smooth strain-softening curve dropping to 5.647 MPa at fR4. The neural network successfully navigates these diverse mechanical typologies sequentially (Figure 7), without exhibiting the erratic algorithmic artefacts that characterise pure data-driven approaches.
Figure 7.
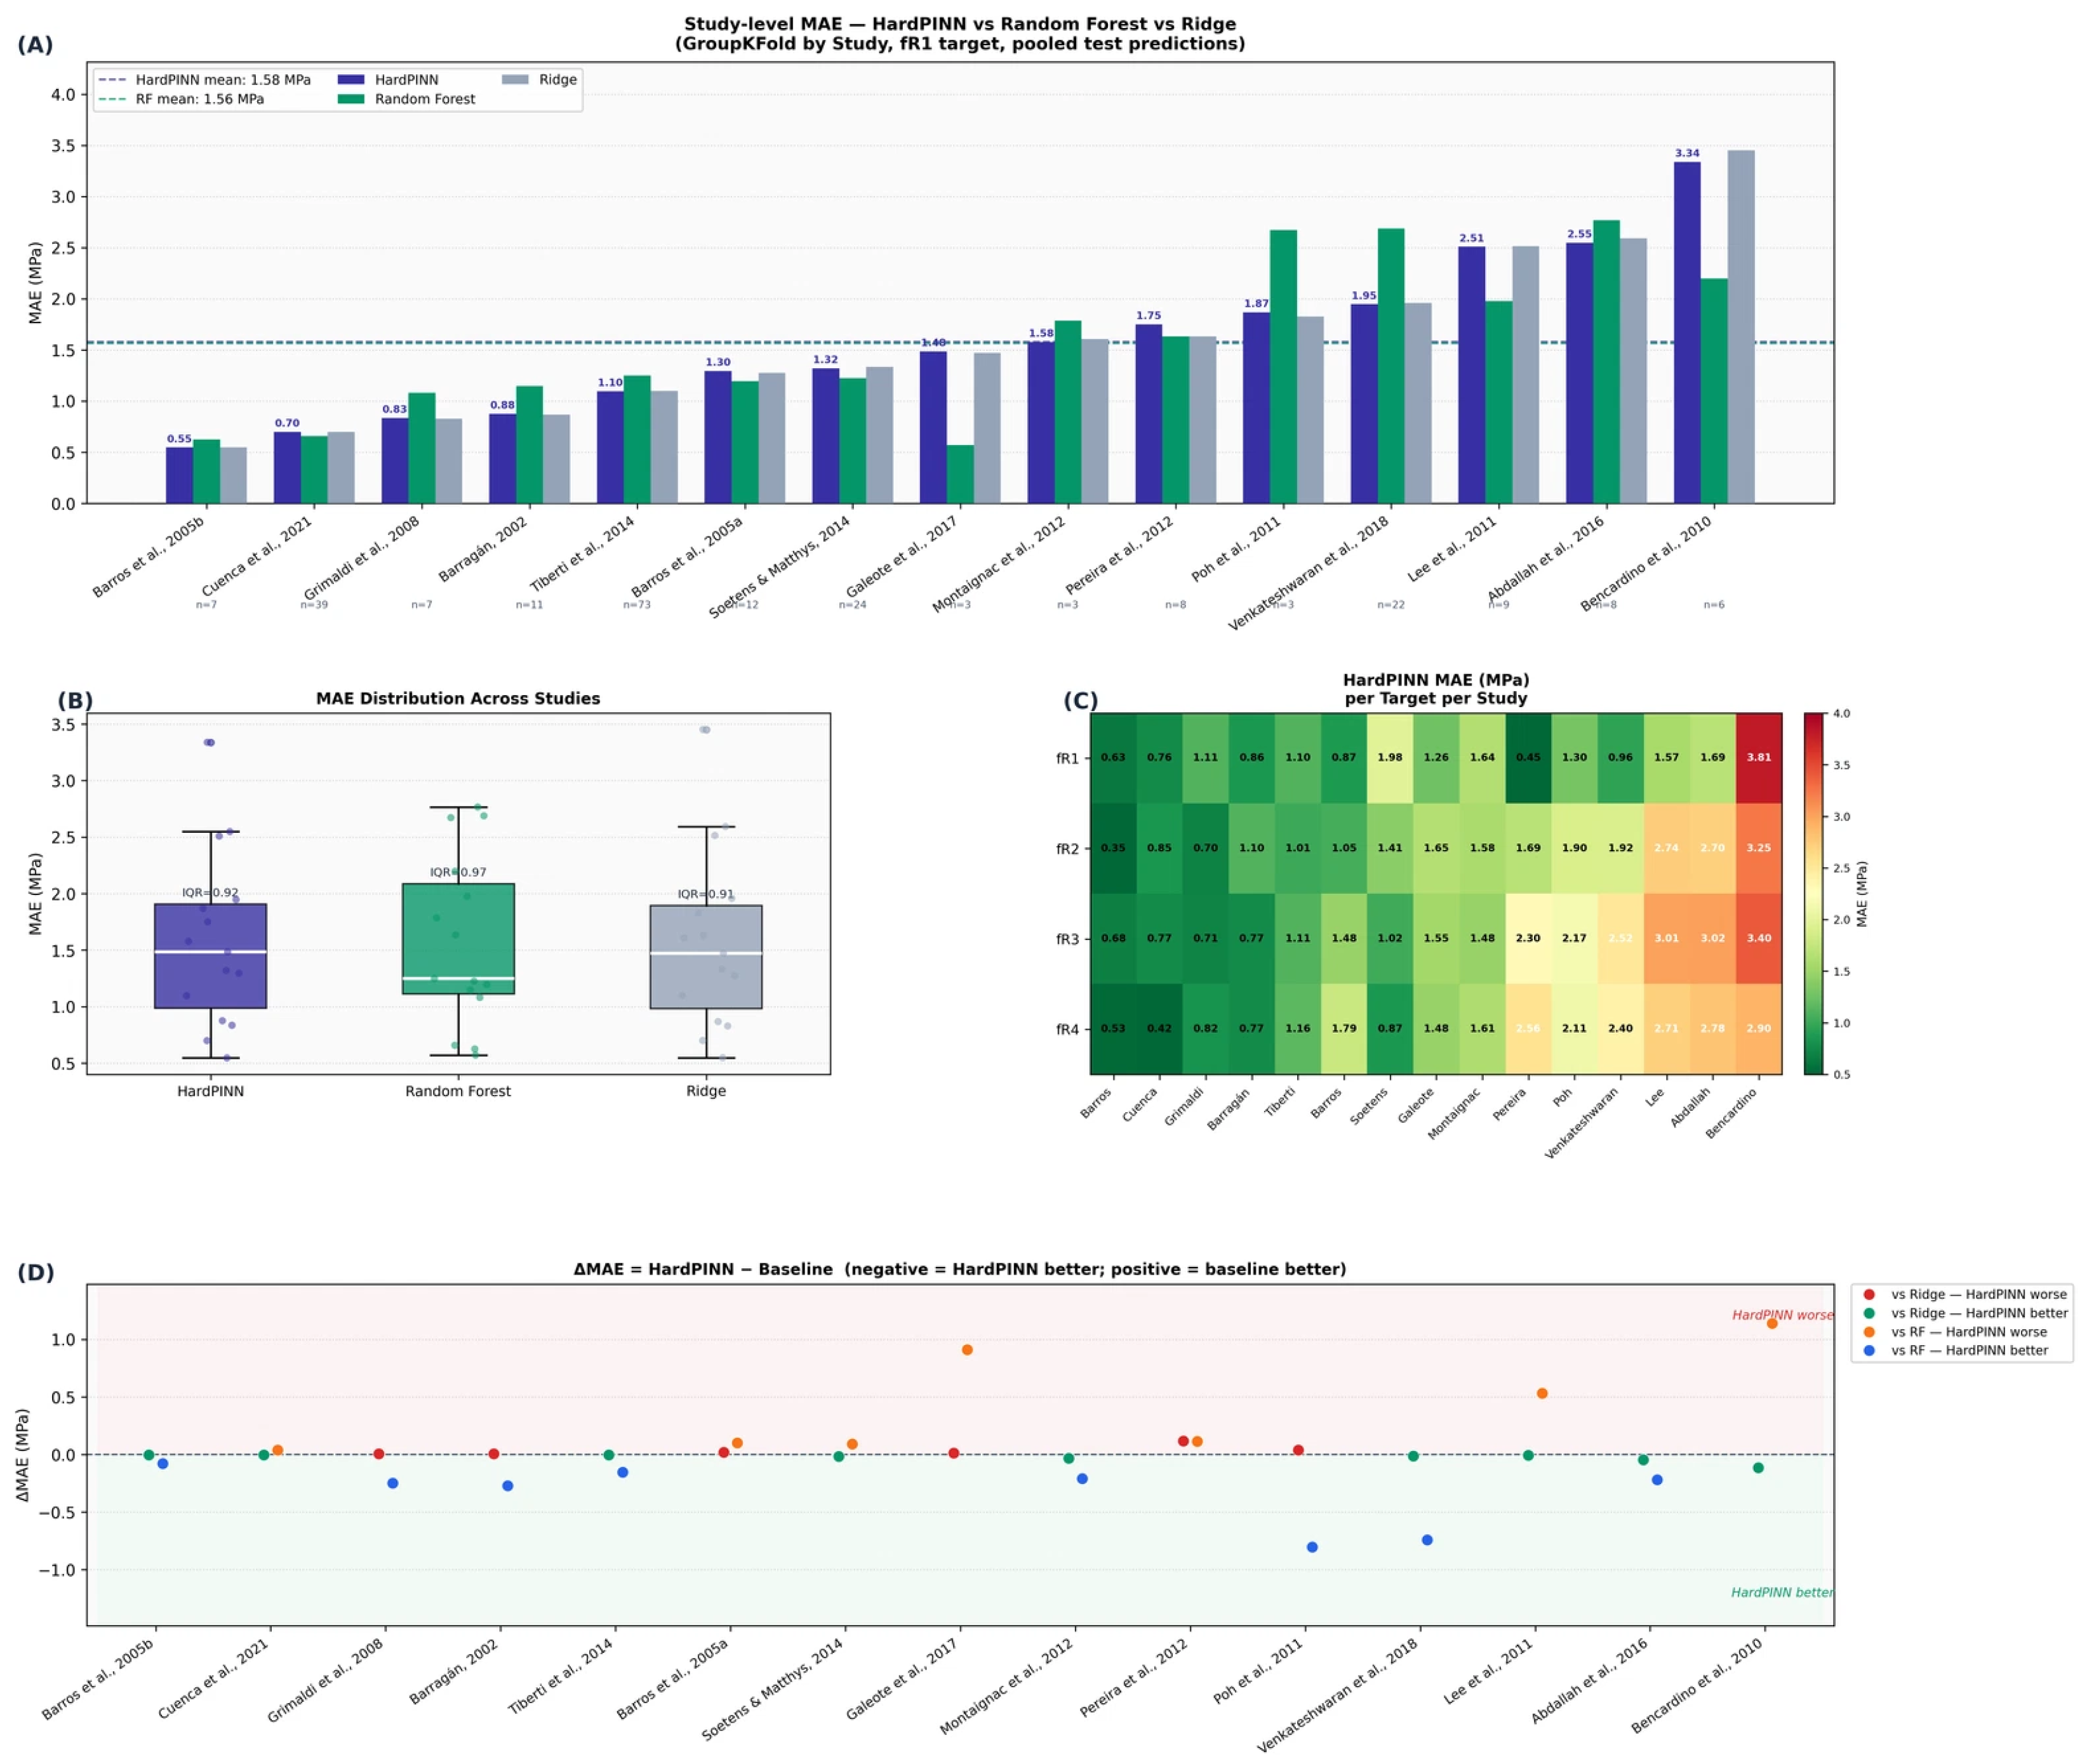
Study-level prediction error distribution under group-based cross-validation. The PCNN exhibits reduced variability across independent experimental datasets. Out-of-distribution model performance evaluated across experimental studies. (A) Box plots comparing study-level Mean Absolute Error (MAE) for fR1 across Ridge Regression, Random Forest, and PCNN using 5-fold GroupKFold cross-validation; lower values indicate superior cross-study generalization (B) Ridge Regression, (C) Random Forest, and (D) HardPINN. Rows correspond to individual studies (first author and publication year), with darker shading indicating larger prediction errors [26].
3.7. Implications of Outcomes
A primary limitation of the present study lies in the scope of the underlying empirical dataset. Whilst the PINN architecture is trained on an expanded dataset comprising 860 observations, these data points are derived from 18 foundational independent experimental studies. The empirical variability captured by the model is fundamentally tethered to the breadth and diversity of these initial sources. Although the governing physical laws enforced through the loss function help regularise the model and mitigate overfitting within the explored domain, the generalisability of the predictions remains bounded by this initial sample size. Future work should prioritise expanding the primary experimental database through targeted laboratory testing to further substantiate the robustness and predictive reliability of the proposed framework.
The findings in this investigation highlight a necessary evolution in how computational mechanics approaches the application of artificial intelligence. The field is progressively transitioning from purely empirical, data-driven algorithms toward physically constrained, structurally grounded methodologies.
The fundamental paradox revealed by this study is that superior statistical fit does not inherently equate to superior engineering viability. Traditional evaluation protocols—specifically those employing random data partitioning—often hide the limitations of unconstrained models by confusing interpolative memorisation with genuine generalisation. When subjected to rigorous, independently executed experimental campaigns, unconstrained models like Ridge regression may minimise error globally, but their inability to respect the foundational laws of physics restricts their utility in safety-critical structural design.
The PCNN architecture mitigates this critical limitation. By embedding domain knowledge directly into the topological geometry of the neural network—enforcing monotonicity, non-negativity, and sequential coherence by mathematical construction—the algorithmic hypothesis space is restricted strictly to physically mechanical-based admissible solutions. While this structural imposition introduces a slight degradation in traditional statistical metrics due to the bias-variance trade-off, it actively reduces the network from generating mechanically impossible design recommendations.
In the advancing framework of complex infrastructure, ensuring that predictive computational systems are constrained by physical reality is paramount. The proposed framework provides physically admissible, interpretable predictions of residual flexural strengths. However, the fold-to-fold R2 variability—notably for fR4, where cross-validation standard deviation reaches 0.480—indicates that predictive accuracy is substantially domain-dependent. Generalisation to studies with fibre geometries, aggregate interlocking conditions, or casting procedures outside the training distribution cannot be assumed without additional validation data. The framework is robust in the sense of guaranteed physical admissibility; it is not robust in the sense of study-invariant predictive accuracy.
3.8. Future Research Directions
While the current framework of the PCNN successfully bounds the post-cracking behaviour of SFRC, significant avenues remain for its conceptual expansion. Future investigative efforts should focus on extending these hard architectural constraints to encompass temporal degradation phenomena, specifically capturing the monotonic decay of structural capacity under long-term creep, fatigue cycling, and aggressive environmental chloride ingress.
Furthermore, moving beyond macroscopic empirical metrics, the direct embedding of energy-based fracture mechanics—such as prescribing strict thermodynamic bounds on the dissipated fracture energy (GF) during crack propagation—could grant the network a highly granular, constitutive understanding of the failure surface of materials. Integrating this physics-informed architecture with advanced Bayesian inference networks represents a critical avenue for future development. Such an integration would facilitate formal uncertainty quantification, transitioning the outputs from deterministic point predictions into mechanistically bounded probability distributions. Ultimately, integrating these constrained intelligence models into real-time Digital Twin frameworks represents the definitive frontier for next-generation structural health monitoring and predictive maintenance of the civil infrastructure.
4. Conclusions
This study proposed a PCNN for predicting the residual flexural strengths fR1–fR4 of steel fibre reinforced concrete. Three physical constraints—non-negativity (softplus output), monotonic dependence on reinforcement index (NonNegDense layer), and bounded sequential evolution across CMOD stages (BetaTanh layer)—are enforced architecturally, guaranteeing admissibility by construction for all possible input configurations, not just those observed in training.
The model was trained and evaluated on 235 original beam specimens from 18 experimental groups, expanded to 860 observations via controlled integer replication (×2–×6). Evaluation used GroupKFold by Study (n = 5) to eliminate data leakage across experimental campaigns. Key quantitative findings: PCNN achieves fR1 MAE = 1.256 MPa and R2 = 0.606, competitive with Ridge (MAE = 1.144, R2 = 0.688) and superior to GBDT (MAE = 1.250, R2 = 0.622)—the most flexible unconstrained benchmark. Random Forest and GBDT exhibit monotonicity violations in 7.3% and 10.2% of checks; PCNN: 0% by proof.
The practical implication is direct: for structural design under fib Model Code 2010 and EN 14651, predictions of fR1–fR4 must satisfy non-negativity and be mechanically consistent across CMOD stages. PCNN satisfies these conditions without post-processing; no unconstrained model does.
Several limitations bound the transferability of the current framework. First, the database comprises 18 experimental studies; fold-to-fold R2 variability—fR1 SD = 0.233, fR4 SD = 0.480—reflects the domain shift between held-out studies and is the primary constraint on generalizability. Predictions for SFRC mixes, fibre types, or casting conditions outside this distribution should be treated as extrapolation until additional experimental validation is available. Second, fibre orientation effects and specimen geometry are not explicitly modelled. Third, the 15% internal validation split used for early stopping is not group-aware, introducing a minor source of leakage into the training procedure. Future work should expand the primary experimental database, develop a group-aware early stopping strategy, quantify prediction uncertainty via conformal or Bayesian extensions of the constrained architecture, and validate against full-scale structural tests.
Supplementary Materials
The following supporting information can be downloaded at: https://www.mdpi.com/article/10.3390/buildings16204160/s1, S1. Supplementary Material: Theoretical Background and Conceptual Framework; S2. Model Summary; S3. Neural Network Architecture and Hard-Constraint Formulation.
Author Contributions
C.Á.: Conceptualisation, Data collection, Analysis of Results, Definition of methodology, Writing—review and editing, Supervision. E.D.R.T.: Analysis of Results, Definition of methodology Writing—draft, Definition of methodology. J.C.: Conceptualisation, Writing—review and editing, Data collection, Supervision. All authors have read and agreed to the published version of the manuscript.
Funding
Julian Carrillo thanks Vicerrectoría de Investigaciones at Universidad Militar Nueva Granada for providing research grants.
Data Availability Statement
Data available on request from the authors.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| RI | Reinforcement Index |
| Vf | Volume fraction |
| HSC | High-strength concrete |
| SCC | Self-compacting concrete |
| HS-SCC | High-strength self-compacting concrete |
| HSC-SCC | Hybrid HSC/SCC |
| HPSFC | High-performance steel fibre concrete |
| CC | Conventional concrete |
| PINN | Physics-Informed Neural Network |
| PCNN | Physics-Constrained Neural Network |
| EDA | Exploratory Data Analysis |
| SFRC | Steel Fibre Reinforced Concrete |
| 3PBT | Three-point bending test |
| VIF | Variance Inflation Factor |
References
- Roumaldi, J.P.; Batson, G. Mechanics of Crack Arrest in Concrete. J. Eng. Mech.-Asce 1963, 89. [Google Scholar] [CrossRef] [Scilit]
- Naaman, A.E.; Shah, S.P. Pull-Out Mechanism in Steel Fiber-Reinforced Concrete. ASCE J. Struct. Div. 1976, 102, 1537–1548. [Google Scholar] [CrossRef] [Scilit]
- Hillerborg, A.; Modéer, M.; Petersson, P.-E. Analysis of crack formation and crack growth in concrete by means of fracture mechanics and finite elements. Cem. Concr. Res. 1976, 6, 773–781. [Google Scholar] [CrossRef] [Scilit]
- Zheng, D.; Wu, R.; Sufian, M.; Ben Kahla, N.; Atig, M.; Deifalla, A.F.; Accouche, O.; Azab, M. Flexural Strength Prediction of Steel Fiber-Reinforced Concrete Using Artificial Intelligence. Materials 2022, 15, 5194. [Google Scholar] [CrossRef] [Scilit]
- Hiew, S.Y.; Bin Teoh, K.; Wong, H.S.; Banthia, N.; Yoo, D.-Y. Recent advances in low-carbon ultra-high-performance concrete: Materials, mechanisms, and sustainability perspectives. npj Mater. Sustain. 2026, 4, 3. [Google Scholar] [CrossRef] [Scilit]
- Zhang, X.; Wu, Z.; Xie, J.; Hu, X.; Shi, C. Trends toward lower-carbon ultra-high performance concrete (UHPC)—A review. Constr. Build. Mater. 2024, 420, 135602. [Google Scholar] [CrossRef] [Scilit]
- Jin, A.H.; Woo, J.S.; Yun, H.D.; Kim, S.W.; Park, W.S.; Choi, W.C. Influence of concrete strength and fiber properties on residual flexural strength of steel fiber-reinforced concrete. Constr. Build. Mater. 2025, 489, 142366. [Google Scholar] [CrossRef] [Scilit]
- EN-14651-2005-A1-2008; Test Method for Metallic Fibre Concrete—Measuring the Flexural Tensile Strength (Limit of Proportionality (LOP), Residual). European Committee for Standardization: Brussels, Belgium, 2007.
- ASTM C1609/C1609M—06; Standard Test Method for Flexural Performance of Fiber-Reinforced Concrete (Using Beam with Third-Point Loading). American Society for Testing and Materials: West Conshohocken, PA, USA, 2019. [Google Scholar] [CrossRef] [Scilit]
- Fédération Internationale du Béton. Model Code 2010; International Federation for Structural Concrete (fib): Lausanne, Switzerland, 2012. [Google Scholar]
- ACI Committee 318. Building Requirements for Structural Concrete and Commentary; American Concrete Institute: Farmington Hills, MI, USA, 2019; Volume 1. [Google Scholar]
- Carrillo, J.; Vargas, J.D.; Arroyo, O. Correlation between Flexural–Tensile Performance of Concrete Reinforced with Hooked-End Steel Fibers Using US and European Standards. J. Mater. Civ. Eng. 2021, 33, 04021211. [Google Scholar] [CrossRef] [Scilit]
- Ministerio de Fomento. Código Estructural; Ministerio de Fomento: Madrid, Spain, 2021. [Google Scholar]
- EN 1998-1; Eurocode 8: Design of Structures for Earthquake Resistance—Part 1: General Rules, Seismic Actions and Rules for Buildings. European Union: Brussels, Belgium, 2004.
- Portilla, S.; Reyes, J.C.; Carrillo, J.; Lasso, J.E. Mechanical properties of masonry using artificial neural networks. Earthq. Spectra 2025, 41, 1536–1564. [Google Scholar] [CrossRef] [Scilit]
- Arroyo, O.; Angarita, C.; Montes, C.; Bonett, R.; Carrillo, J. Machine Learning-Based Evaluation of Roof Drifts and Accelerations of Reinforced Concrete Wall Buildings During Ground Motions. Earthq. Spectra 2026, 42, e70018. [Google Scholar] [CrossRef] [Scilit]
- Shafighfard, T.; Kazemi, F.; Bagherzadeh, F.; Mieloszyk, M.; Yoo, D.Y. Chained machine learning model for predicting load capacity and ductility of steel fiber–reinforced concrete beams. Comput.-Aided Civil. Infrastruct. Eng. 2024, 39, 3573–3594. [Google Scholar] [CrossRef] [Scilit]
- Avila, C.; Shiraishi, Y.; Tsuji, Y. Crack Width Prediciton of Reinforced Concrete Structures by Artificial Neural Networks. In Proceedings of the 7th Seminar on Neural Network Applications in Electrical Engineering, 2004. NEUREL 2004. 2004; IEEE: New York, NY, USA, 2004; pp. 39–44. [Google Scholar] [CrossRef] [Scilit]
- Ikumi, T.; Galeote, E.; Pujadas, P.; de la Fuente, A.; López-Carreño, R.D. Neural network-aided prediction of post-cracking tensile strength of fibre-reinforced concrete. Comput. Struct. 2021, 256, 106640. [Google Scholar] [CrossRef] [Scilit]
- Congro, M.; Monteiro, V.M.d.A.; Brandão, A.L.; dos Santos, B.F.; Roehl, D.; Silva, F.d.A. Prediction of the residual flexural strength of fiber reinforced concrete using artificial neural networks. Constr. Build. Mater. 2021, 303, 124502. [Google Scholar] [CrossRef] [Scilit]
- Kapoor, S.; Narayanan, A. Leakage and the reproducibility crisis in machine-learning-based science. Patterns 2023, 4, 100804. [Google Scholar] [CrossRef] [Scilit]
- Kang, M.C.; Yoo, D.Y.; Gupta, R. Machine learning-based prediction for compressive and flexural strengths of steel fiber-reinforced concrete. Constr. Build. Mater. 2021, 266, 121117. [Google Scholar] [CrossRef] [Scilit]
- Raissi, M.; Perdikaris, P.; Karniadakis, G.E. Physics-informed neural networks: A deep learning framework for solving forward and inverse problems involving nonlinear partial differential equations. J. Comput. Phys. 2019, 378, 686–707. [Google Scholar] [CrossRef] [Scilit]
- Faroughi, S.A.; Pawar, N.M.; Fernandes, C.; Raissi, M.; Das, S.; Kalantari, N.K.; Mahjour, S.K. Physics-Guided, Physics- Informed, and Physics-Encoded Neural Networks and Operators in Scientific Computing: Fluid and Solid Mechanics. J. Comput. Inf. Sci. Eng. 2024, 24, 040802. [Google Scholar] [CrossRef] [Scilit]
- Cáceres, M.; Avila, C.; Rivera, E. Thermodynamics-Informed Neural Networks for the Design of Solar Collectors: An Application on Water Heating in the Highland Areas of the Andes. Energies 2024, 17, 4978. [Google Scholar] [CrossRef] [Scilit]
- Carrillo, J.; Vargas, J.D.; Alcocer, S.M. Model for estimating the flexural performance of concrete reinforced with hooked end steel fibers using three-point bending tests. Struct. Concr. 2021, 22, 1760–1783. [Google Scholar] [CrossRef] [Scilit]
- Cuenca, E.; Conforti, A.; Minelli, F.; Plizzari, G.A.; Navarro Gregori, J.; Serna, P. A material-performance-based database for FRC and RC elements under shear loading. Mater. Struct./Mater. Constr. 2018, 51, 11. [Google Scholar] [CrossRef] [Scilit]
- Barragán, B. Failure and Toughness of Steel Fiber Reinforced Concrete Under Tension and Shear. Ph.D. Thesis, Universitat Politècnica de Catalunya, Barcelona, Spain, 2002. [Google Scholar] [CrossRef] [Scilit]
- Meredig, B.; Antono, E.; Church, C.; Hutchinson, M.; Ling, J.; Paradiso, S.; Blaiszik, B.; Foster, I.; Gibbons, B.; Hattrick-Simpers, J.; et al. Can machine learning identify the next high-temperature superconductor? Examining extrapolation performance for materials discovery. Mol. Syst. Des. Eng. 2018, 3, 819–825. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.