


Abstract
Traditional DEA models can neither effectively handle fuzzy random variables nor achieve a complete ranking of decision-making units (DMUs). Based on the conventional fuzzy stochastic DEA model, this study introduces an exponential distribution extension. By incorporating fuzzy random variables, it significantly simplifies the deterministic transformation of chance-constrained models. Moreover, most existing DEA ranking methods only consider the relative efficiencies among DMUs while ignoring their internal structural characteristics. To address this issue, we develop a deterministic model for the exponentially extended fuzzy stochastic DEA and design a weight formula that reflects the internal input–output structure of each DMU. This approach makes the complete ranking of DMUs more reasonable and better aligned with practical situations. Finally, the rationality and effectiveness of the proposed model are verified through a comparative analysis of rankings obtained from different DEA models. The results indicate that the input–output structure within a decision-making unit plays a significant role in its efficiency ranking.
Keywords:
extended exponential distribution; fuzzy random variable; chance-constrained programming; factor analysis; complete ranking MSC:
90B50
1. Introduction
Data Envelopment Analysis (DEA) as a non-parametric efficiency evaluation method, has been widely applied in various fields since the CCR model was proposed by Charnes et al. [1] (1978). This approach constructs a production frontier to assess the relative efficiency of DMUs under multiple inputs and multiple outputs without requiring a pre-specified production function, offering advantages such as strong objectivity and the ability to handle multi-dimensional indicators. However, with the deepening of research and the expansion of practical applications, two major challenges inherent in traditional DEA models have become increasingly prominent. First, input and output data in real-world scenarios often exhibit uncertainty characterized by fuzziness and randomness, making it difficult for conventional deterministic models to accurately depict efficiency frontiers. Second, it is difficult to achieve a complete ranking with traditional DEA models. Combining fuzzy DEA with factor analysis ranking theory not only resolves the issue that traditional DEA models cannot determine the efficiency of DMUs in a fuzzy environment, but also enhances the ability to further identify high-efficiency DMUs.
1.1. Research Status of Uncertain DEA
In response to the pervasive data uncertainty in real-world decision-making environments, scholars have expanded the theoretical boundaries of traditional DEA models through various approaches. Overall, existing research can be categorized into three main streams: fuzzy DEA [2], stochastic DEA [3] and robust DEA [4], each exhibiting significant differences in the characterization and handling of uncertainty. Fuzzy DEA deals with epistemic uncertainty, where the data themselves are inherently vague, linguistic, or ambiguous. Stochastic DEA addresses aleatory uncertainty, meaning that the data exhibit random fluctuations whose distributional characteristics (e.g., mean, variance) can be estimated from historical data. When input–output data are assumed to be random variables, stochastic DEA evaluates efficiency using chance-constrained DEA (CCDEA) or stochastic frontier analysis (SFA). Robust DEA, on the other hand, handles deep uncertainty that encompasses both data and distribution, i.e., neither the exact values of the data nor their underlying probability distributions are known; all that is known is that the data lie within a given interval or an uncertainty set. In recent years, mixed research combining these three types of uncertainty-oriented DEA methods has been growing rapidly.
Fuzzy DEA methods represent an important branch for addressing data uncertainty. These approaches treat input–output data as fuzzy numbers (e.g., triangular fuzzy numbers, trapezoidal fuzzy numbers) and evaluate efficiency through fuzzy programming or membership function transformation. Kao and Liu [5] (2000) proposed an early fuzzy DEA framework based on fuzzy membership levels, converting fuzzy data into interval efficiency values under different level sets. Jahanshahloo [6] et al. (2009) further developed a fuzzy DEA ranking method based on the -norm, achieving complete ranking of DMUs in fuzzy environments through distance measures. Luhaniwal [7] et al. (2025) applied fuzzy DEA models to the field of renewable energy evaluation in India, validating the practical value of fuzzy methods in energy decision-making. However, traditional fuzzy DEA methods exhibit limitations in handling probabilistic uncertainty; fuzzy membership functions reflect “possibility” rather than “probability”, making it difficult to characterize random fluctuations with statistical distributional properties.
Stochastic DEA methods address uncertainty from the perspective of probability theory. The chance-constrained programming approach proposed by Cooper [8] et al. (2004) constitutes foundational work in this area, transforming stochastic constraints into deterministic equivalents by introducing significance levels. This approach assumes that input–output data follow certain probability distributions (e.g., normal or exponential distributions) and satisfy constraints at a given confidence level. In recent years, Abdolazimi [9] et al. (2025) introduced a novel framework combining stochastic DEA and GARMA models to evaluate the efficiency of water and sewerage companies under uncertainty and undesirable outputs, capturing random and time-dependent dynamics. The approach enables proactive identification of inefficiencies and vulnerabilities, supporting optimized resource allocation, maintenance planning, and sustainable environmental management. However, stochastic DEA relies heavily on assumptions about probability distributions; in practical applications, when data distributions are difficult to accurately identify, the robustness of evaluation results may be compromised.
Robust DEA methods, as a third approach, characterize the range of parameter fluctuations by constructing uncertainty sets, seeking efficiency evaluations that remain valid even under “worst-case” scenarios. Arabmaldar [10] et al. (2024) addressed the conservatism issue in robust DEA models by introducing a novel model with variable budgeted uncertainty, which reduced the price of robustness by approximately 20% compared to existing approaches. The proposed method also provided probabilistic bounds for constraint violations and demonstrated its practical applicability using a large-scale grocery retail dataset. The advantage of robust methods lies in their lack of requirement for precise probability distribution information, although their conservatism may lead to overly pessimistic efficiency evaluations.
Each of the three aforementioned methods has its own focus, yet none simultaneously address the fuzziness and randomness that may coexist in data. In practice, enterprise operational data often exhibit both types of uncertainty: fuzziness arises from measurement errors, subjective judgments, etc., while randomness stems from market fluctuations, policy changes, etc. Fuzzy stochastic DEA methods attempt to integrate the two paradigms; for instance, Peykani [11] et al. (2019) proposed a novel fuzzy DEA model based on a general fuzzy measure that incorporates optimistic–pessimistic parameters, allowing the attitude to be customized for each DMU. The approach is more flexible than traditional possibility, necessity, or credibility measures, and its applicability is demonstrated using a real dataset of 38 U.S. hospitals. Omrani et al. (2022) [12] proposed a robust credibility DEA (RCDEA) model that integrates fuzzy credibility and robust optimization to handle data uncertainty, and applied it to evaluate 28 hospitals in Iran, showing that efficiency decreases as the perturbation degree increases. Özçalici et al. (2026) [13] proposed a hybrid multi-criteria decision-making (MCDM) framework that integrates Fuzzy LBWA and a modified ARTASI method, along with Decision Stability Intervals (DSI) and Monte Carlo simulations, to evaluate the performance of global insurance brokers under uncertainty. The results reveal a consistent performance hierarchy among top brokers, with liquidity ratios showing the widest stability ranges and profitability indicators being the most critical for ranking robustness. Wang et al. (2025) [14] proposed a systematic approach combining AHP and fuzzy set theory to assess organizational vulnerability in nuclear power plants, with a case study confirming low vulnerability and high reliability, thereby enhancing safety and sustainability in the nuclear power sector.
However, most of the aforementioned studies employ triangular fuzzy numbers and primarily combine fuzzy set theory with MCDM methods, which suffer from strong subjectivity, lack of dimensionality reduction, and an inability to uncover latent structures. To address these limitations, the present study adopts factor analysis to explore the input–output structure of DMUs. Furthermore, few of these studies consider that fuzzy variables may also exhibit randomness. Therefore, we employ the more flexible trapezoidal fuzzy numbers, which degenerate into triangular fuzzy numbers when the kernel collapses to a single value. This approach adapts to real-world conditions better and accounts for fuzzy random variables that follow an exponential distribution.
1.2. Research Status of DEA Ranking
The issue of DEA ranking emerged alongside the development of efficiency evaluation methods. Traditional CCR models classify DMUs into efficient units (efficiency score = 1) and inefficient units (efficiency score < 1). However, when multiple DMUs lie on the production frontier simultaneously, further differentiation among them becomes impossible. This “efficient unit differentiation dilemma” has prompted extensive research into ranking methods.
The super-efficiency model represents the most classical approach to addressing the ranking problem. The AP model proposed by Andersen and Petersen [15] (1993) removes the evaluated unit from the reference set and recalculates its efficiency, allowing efficient units to achieve efficiency scores greater than 1, thereby enabling differentiation. Nevertheless, the AP model suffers from infeasibility issues in certain cases—when the removed unit defines specific dimensions of the production frontier, the new production frontier may not be effectively constructed. Zhu [16] (2001) and Mehrabian [17] et al. (1999) proposed that the potential infeasibility of ultra-efficient DEA models is related solely to extremely efficient decision-making units and proposed an alternative efficiency metric based on different optimization problems.
The cross-efficiency method offers an alternative ranking approach. This method calculates the average efficiency of each DMU using the optimal weights of all DMUs, mitigating the influence of extreme weights by combining “self-evaluation” with “peer-evaluation”. Doyle [18] et al. (1994) developed the concept of cross-efficiency in DEA as a peer-appraisal alternative to self-appraisal; the authors presented three formulations for aggressive and benevolent cross-efficiency, and empirically compared two of them on a real dataset while suggesting practical applications, and subsequent research has extensively explored issues such as weight determination methods [19] and secondary objective selection [20]. However, the cross-efficiency method depends on the selection of specific weight solutions, and different secondary objectives may lead to divergent ranking outcomes.
Ranking decision-making units (DMUs) based solely on conventional DEA efficiency scores often leaves multiple units tied at the efficient frontier. Multi-stage ranking methods transform the ranking problem into a multi-level decision-making process. Seiford and Zhu [21] (2003) proposed context-dependent DEA, which constructs efficiency hierarchies by iteratively removing efficient units, enabling progressive ranking. Wang [22] et al. (2006) introduces ideal and anti-ideal DMUs into DEA to generate best-possible and worst-possible relative efficiencies, which are then combined into a relative closeness (RC) index for overall ranking of DMUs. Two numerical examples illustrate the proposed models and the RC index. In addition, ranking methods based on multi-attribute decision-making have gained considerable attention in recent years. These approaches treat DEA efficiency scores as one evaluation dimension and combine them with other indicators for comprehensive ranking. For instance, Tavana [23] et al. (2015) proposed a hybrid fuzzy multi-criteria decision-making (MCDM) method combining DEMATEL, fuzzy ANP, and two modified fuzzy DEA models under BSC criteria to evaluate pharmaceutical companies on the Swiss Stock Exchange, with a Shannon entropy-based ranking to assist investors in portfolio selection under uncertainty. Kehinde [24] et al. (2025) presented an integrated SET-DEA-IDEA framework that objectively ranks equities by first using Shannon entropy for variable selection, then DEA to identify efficient stocks, and finally inverse DEA to rank them based on adaptability to output changes, as demonstrated on Taiwan’s tourism sector stocks. And the entropy weight method [25] is used to objectively determine indicator weights. Jahanshahloo [26] et al. (2006) extended the entropy-TOPSIS method to handle fuzzy decision-making problems by representing criteria weights and alternative ratings as triangular fuzzy numbers and using -cuts for normalization, with a numerical example illustrating the procedure. Although these hybrid methods achieve complete ranking, the additional subjective decision parameters introduced may affect the robustness of the evaluation results. Finally, ranking methods based on weight space exploration represent a recent frontier. Lei [27] et al. (2026) proposed the Dominance Efficiency Probability (DEP) framework, which employs a grid generation algorithm to systematically sample the weight space, computes pairwise dominance probabilities among DMUs, and subsequently obtains ranking expectations and ranking variances. This approach avoids dependence on specific weight solutions, yielding reproducible evaluation results, albeit with high computational complexity.
Each of the aforementioned ranking methods has its respective advantages and disadvantages, yet they commonly share a fundamental limitation: the ranking process relies solely on efficiency values and fails to effectively incorporate differentiated information regarding the input–output structural characteristics of DMUs. In other words, two DMUs with identical efficiency scores are considered “equivalent” in ranking, whereas in reality, their input allocation structures and output composition patterns may differ significantly, and these differences should ideally be reflected in the ranking outcomes.
Currently, research addressing uncertain DEA and DMU ranking remains limited, with most studies focusing solely on relative efficiency between decision units, such as cross-efficiency models based on fuzzy DEA. Building upon the construction of fuzzy stochastic deterministic DEA with extended exponential distribution, this study introduces factor analysis theory to assign differentiated weights to decision units based on an analysis of their input–output structures, thereby achieving complete ranking. The main contributions of this study are as follows: (1) proposing fuzzy random variables with extended exponential distribution, capable of accommodating engineering problems characterized by exponential distribution; (2) constructing a fuzzy stochastic deterministic DEA model through Lemma 1, reflecting the optimistic attitude of decision-makers; and (3) introducing factor analysis to render the ranking of decision units more comprehensive and accurate.
2. Construction of Fuzzy Stochastic DEA Model
On the one hand, given the prominent status of the DEA model in the field of efficiency evaluation, and on the other hand, considering the limitations of traditional DEA models in applications involving complex systems, this study improves upon the conventional model by constructing a fuzzy stochastic DEA model. This approach leverages the strengths of DEA while extending its applicability to uncertain environments.
2.1. Extended Exponential Distribution
To extend the fuzzy stochastic DEA model for the exponential distribution, we define the following parameters, as shown in Table 1.
Table 1.
Symbols and explanations.
Definition 1.
Density Function and Cumulative Distribution Function [29].
Let be a fuzzy random variable. We say that has an extended exponential distribution, where is a trapezoidal fuzzy number, and:
where denote the density function and cumulative distribution function of the fuzzy exponential random variable, respectively. is a mapping established by through level sets (-cut) or the precise value after deblurring [26].
The above Definition 1 separates the fuzziness and randomness of the variables. The rate parameter of the exponential distribution is an exact number representing randomness, while represents the fuzziness of the mean. The numerical values of the density function and cumulative distribution function of the fuzzy random variable are not affected by fuzziness; the domain is extended to fuzzy numbers, and the numerical values are influenced only by randomness. Therefore, the numerical values of the density function and cumulative distribution function of the fuzzy random variable are equal to those of the density function and cumulative distribution function of the random variable.
Definition 2.
Fuzzy Probability Measure [30].
We define the fuzzy variable :
Let:
where is known input data, generally obtained from observed data, expert estimates, or taken as the central value of the mean trapezoidal fuzzy number. It is worth noting that the above assumption implies that fuzziness has no effect on the variance since is obtained in advance and is an exact number. From Definitions 1 and 2, the following theorem can be obtained:
Proposition 1.
Let be a fuzzy random variable and be an exact number. When the parameter degenerates to an exact number , the following conclusions hold .
Proposition 1 indicates that when evaluating a fuzzy random variable lower than or equal to an exact number, or other inequality relations, fuzziness does not affect the calculation process and can be transformed into the probability measure of a random variable for solution.
Proposition 2.
If , where is a trapezoidal fuzzy number, then:
where .
Proposition 3.
If , where , then:
Based on the above propositions, the following theorem can be obtained.
Theorem 1.
If ,, then:
Proof.
Let . This is because and , Based on the principle of fuzzy extension , it can be regarded as an exact number. Then, . There is an inequality . By Proposition 1, the following can be obtained: . This is due to the properties of the cumulative probability distribution. The proof of the second inequality is similar; this concludes the proof. Then, we transform the fuzzy variable into a deterministic variable through the following lemma. □
Lemma 1.
Let and be two fuzzy numbers with continuous membership functions. For a given confidence level , if and only if , where and denote the left and right endpoints of the -level sets of and , respectively. When , the level sets and are the supports of and , i.e., all points with membership degree greater than 0. When , the part with membership degree greater than or equal to 0.5 is taken. When , the part with membership degree equal to 1 is taken, i.e., the core of the fuzzy numbers [28].
2.2. Fuzzy Stochastic Comprehensive DEA Model
The purpose of this section is to propose a fuzzy stochastic approach for evaluating the efficiency of DMUs with fuzzy stochastic input and output data. The input or output variables in the DEA problem can be fuzzy variables, and their means can follow an exponential distribution.
In this study, we consider fuzzy random variables in the DEA problem. To this end, consider DMUs, where each DMU uses fuzzy stochastic inputs , , to produce fuzzy stochastic outputs , . Let . Correspondingly, and denote a random variable following an exponential distribution.
According to Definition 1, they all have an extended exponential distribution:
where .
Chance-constrained programming is a stochastic optimization model for solving optimization problems with uncertain data, and is particularly suitable for dealing with constraints involving random variables. Its core idea is that the constraints are required to be satisfied with a certain probability, rather than being strictly satisfied in all cases. The objective function is to maximize or minimize a certain goal, such as the efficiency value in the DEA model, and the constraints hold with a certain probability. It is worth noting that the chance-constrained programming model requires the distributions of the random variables to be known or estimable, and the probabilistic form of the constraints needs to be transformed into a computable form (e.g., through Monte Carlo simulation or the inverse function of the distribution function). We propose the following extended DEA model:
If , then is efficient at the extended probability level ; if , then is inefficient at the extended probability level . Here, and represent observed input–output values of the decision-making unit, respectively.
3. Designing Input–Output Weights for Decision-Making Units
The model constructed in the previous section is essentially a DEA model, but with fuzzy random data. Therefore, it still faces the issue of whether complete ranking can be achieved. We consider the following fact: the ranking of a decision-making unit depends not only on its relative efficiency compared to other DMUs, but also on its own input–output structure, i.e., the input–output ratio. For example, suppose enterprise A and enterprise B have the same relative efficiency and both achieve output-oriented DEA efficiency. However, their input emphases are completely different, and neither can be linearly replaced by homogeneous DMUs. If the input–output ratio of A is better than that of B, then enterprise A should be ranked ahead of enterprise B, i.e., a higher weight should be assigned to enterprise A. Therefore, the steps for designing the input–output weights of decision-making units are as follows:
Step 1: Assume there are DMUs, denoted as . Collect the original input–output matrix and denote this matrix as . Separate the inputs and outputs , and record them as the input matrix and the output matrix .
Step 2: Perform data standardization on matrices and . Let the elements of the normalized matrices and be denoted as and . The standard formula is:
where a and b denote the mean values of the variables, while c and d denote the standard deviations of the variables.
Step 3: Calculate the covariance matrices of and . The covariance matrices and are symmetric matrices of and , where and are the numbers of original variables for and , respectively. The element in the covariance matrix C is denoted as , where or . The formula for calculating the elements in the covariance matrix is:
Step 4: Compute the eigenvalues and eigenvectors of the covariance matrices derived from Step 3. Specifically, solve the characteristic equations and to obtain the eigenvalues , and the corresponding eigenvectors , . After normalizing the eigenvectors and , the orthonormal eigenvectors and are obtained.
Step 5: Calculate the variance contribution rate and cumulative variance contribution rate. The variance contribution rate is calculated as follows:
where denotes the kth eigenvalue, which can be used to calculate the variance contribution rate of the kth principal component. Then, the cumulative variance contribution rate is and . The number of eigenvalues when the cumulative variance contribution rate is greater than or equal to 85% [31] represents the number of gray factors.
Step 6: Compute the loading matrix, communalities, and the gray uniqueness diagonal matrix. The procedure is first explained for matrix ; the process for matrix is analogous.
The elements of the loading matrix are calculated using the following formula:
where , and denotes the number of principal components. The meaning of each component is the weight of the jth original variable on the kth principal component direction. denotes the kth column of the loading matrix.
The communality is calculated as follows:
where denotes the number of principal components, and denotes the communality of the jth variable. Equation (6) essentially represents the total contribution of the common factors to the variance of a variable. The gray uniqueness value [32] for the input variable is then given by:
Consequently, the gray uniqueness matrix for the input variables is defined as matrix .
Step 7: Rotate the load matrix using the maximum variance normalization method [33] to obtain the new load matrix . Calculate the commonality matrix and gray uniqueness matrix according to Step 6.
Step 8: Treat the input variables as a vector denoted by , with the number of elements being . The formula for calculating the factor scores of the input variables of is:
The total input gray factor score of the decision-making unit is:
where denotes the normalized commonality of variables after factor rotation, reflecting the weight of each variable. denotes the factor score of the th input variable in , obtained from Formula (9). The score calculation for the output matrix follows a similar approach.
Step 9: This study defines the comprehensive performance factor (CPF), which reflects the net difference between the total gray factor scores of input variables and the total gray factor scores of output variables. It represents the input–output ratio of and is expressed as follows:
The higher the coefficient, the greater the efficiency of the DMU. From the design of the composite score coefficient, it can be seen that the lower the total input factor score of , the higher the composite score coefficient; similarly, the higher the output factor score, the higher the composite score coefficient. Since comprehensively reflects the overall level of output variables through gray-weighted factor scores, and reflects the overall level of input variables, the exponent part directly captures the net effect of output advantages minus input disadvantages.
Step 10: The CPF calculated using Formula (11) can be used to assign corresponding weights to the DMUs, as given by the following formula:
Finally, the weight formula for the decision-making unit considering the input–output structure can be obtained as shown in Equation (13). Therefore, according to Equation (13), the following new model can be obtained:
4. Solution and Optimization of the Stochastic Fuzzy DEA Model
4.1. Deterministic Equivalent Model
Below, we prove that the proposed extended chance-constrained DEA model (14) can be equivalently transformed into a linear programming model using the aforementioned theorems. According to Theorem 1, which gives the equivalent form of fuzzy random variables following an extended exponential distribution in the possibility space at a given level, the output constraint (ii) in model (14) can be transformed as follows:
Based on the representation of L-R fuzzy numbers, and the definition of the left and right endpoints of fuzzy numbers in Lemma 1, under a given threshold , the above relation becomes:
can be obtained:
Similarly, the input constraint (i) in Model (14) can be transformed into the following deterministic constraint:
In summary, based on the definitions and theorems given in the previous two chapters, we gradually transform the initial uncertain constraints of the stochastic fuzzy DEA model into deterministic linear constraints, and finally obtain the deterministic equivalent model of model (14) as follows:
Similarly, the input-oriented deterministic equivalent model is as follows:
4.2. Existence of Model Solutions
First, analyze model (15). Since the terms on the right-hand side of the input constraints are all non-negative, we only need to consider the output terms. Let
the fuzzy extension term is non-positive, and the stochastic term is non-negative. Take , then the output constraint becomes . If , taking satisfies the constraint, and the model is feasible. If even cannot satisfy it, and the model is infeasible. Therefore, the condition for the existence of a feasible solution is:
For given , restricting the upper bound of can make the model solvable. The analysis of the existence of solutions for model (16) is similar, yielding:
5. Comparative Validation
5.1. Sensitivity Analysis of Fuzzy Extension Ranges
To validate the above model, the input–output data of 22 manufacturing enterprises provided by Mengdie Huang et al. [34] are used, these data are presented in Table 2. To conform to the data characteristics of the above model and meet certain application scenarios, the crisp data collected in the table are treated as mean values, and the upper and lower bounds of the fuzzy numbers are calculated as 1%, 5%, 10%, and 20% of the mean, respectively. Furthermore, by adding random noise that follows an exponential distribution, each variable follows an exponential distribution with a mean equal to the observed input or output data and a standard deviation of 1. Therefore, in this case, each DMU is treated as a fuzzy variable with a random mean, as shown in Table 1. This experiment aims to simulate the ranking of DMUs under uncertainty compared with that under deterministic conditions, and to analyze which approach is more robust. This paper adopts model (15), and the DEA model is the output-oriented BCC model.
Table 2.
Original data for organizational quality infrastructure efficiency in 22 manufacturing enterprises set used by Mengdie Huang et al.
By performing a sensitivity analysis using fuzzy expansion on the above data, we obtain Table 3.
Table 3.
Efficiency statistics under different fuzzy expansion ratios.
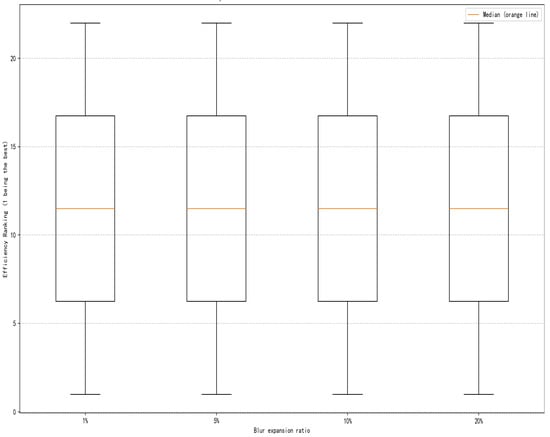
As shown in Table 3, the variation in indicators such as the mean efficiency, standard deviation, and ranking differences is very small across the various ratios (far lower than one standard deviation). The correlation coefficients are all above 0.95 and increase monotonically with the ratio, but the increase is very small (0.014) and is not statistically significant. The maximum average absolute rank difference is 3.45, which represents a moderate deviation among the 22 DMUs; however, the differences between the various ratios are of less than 0.64 ranks and can be considered negligible.
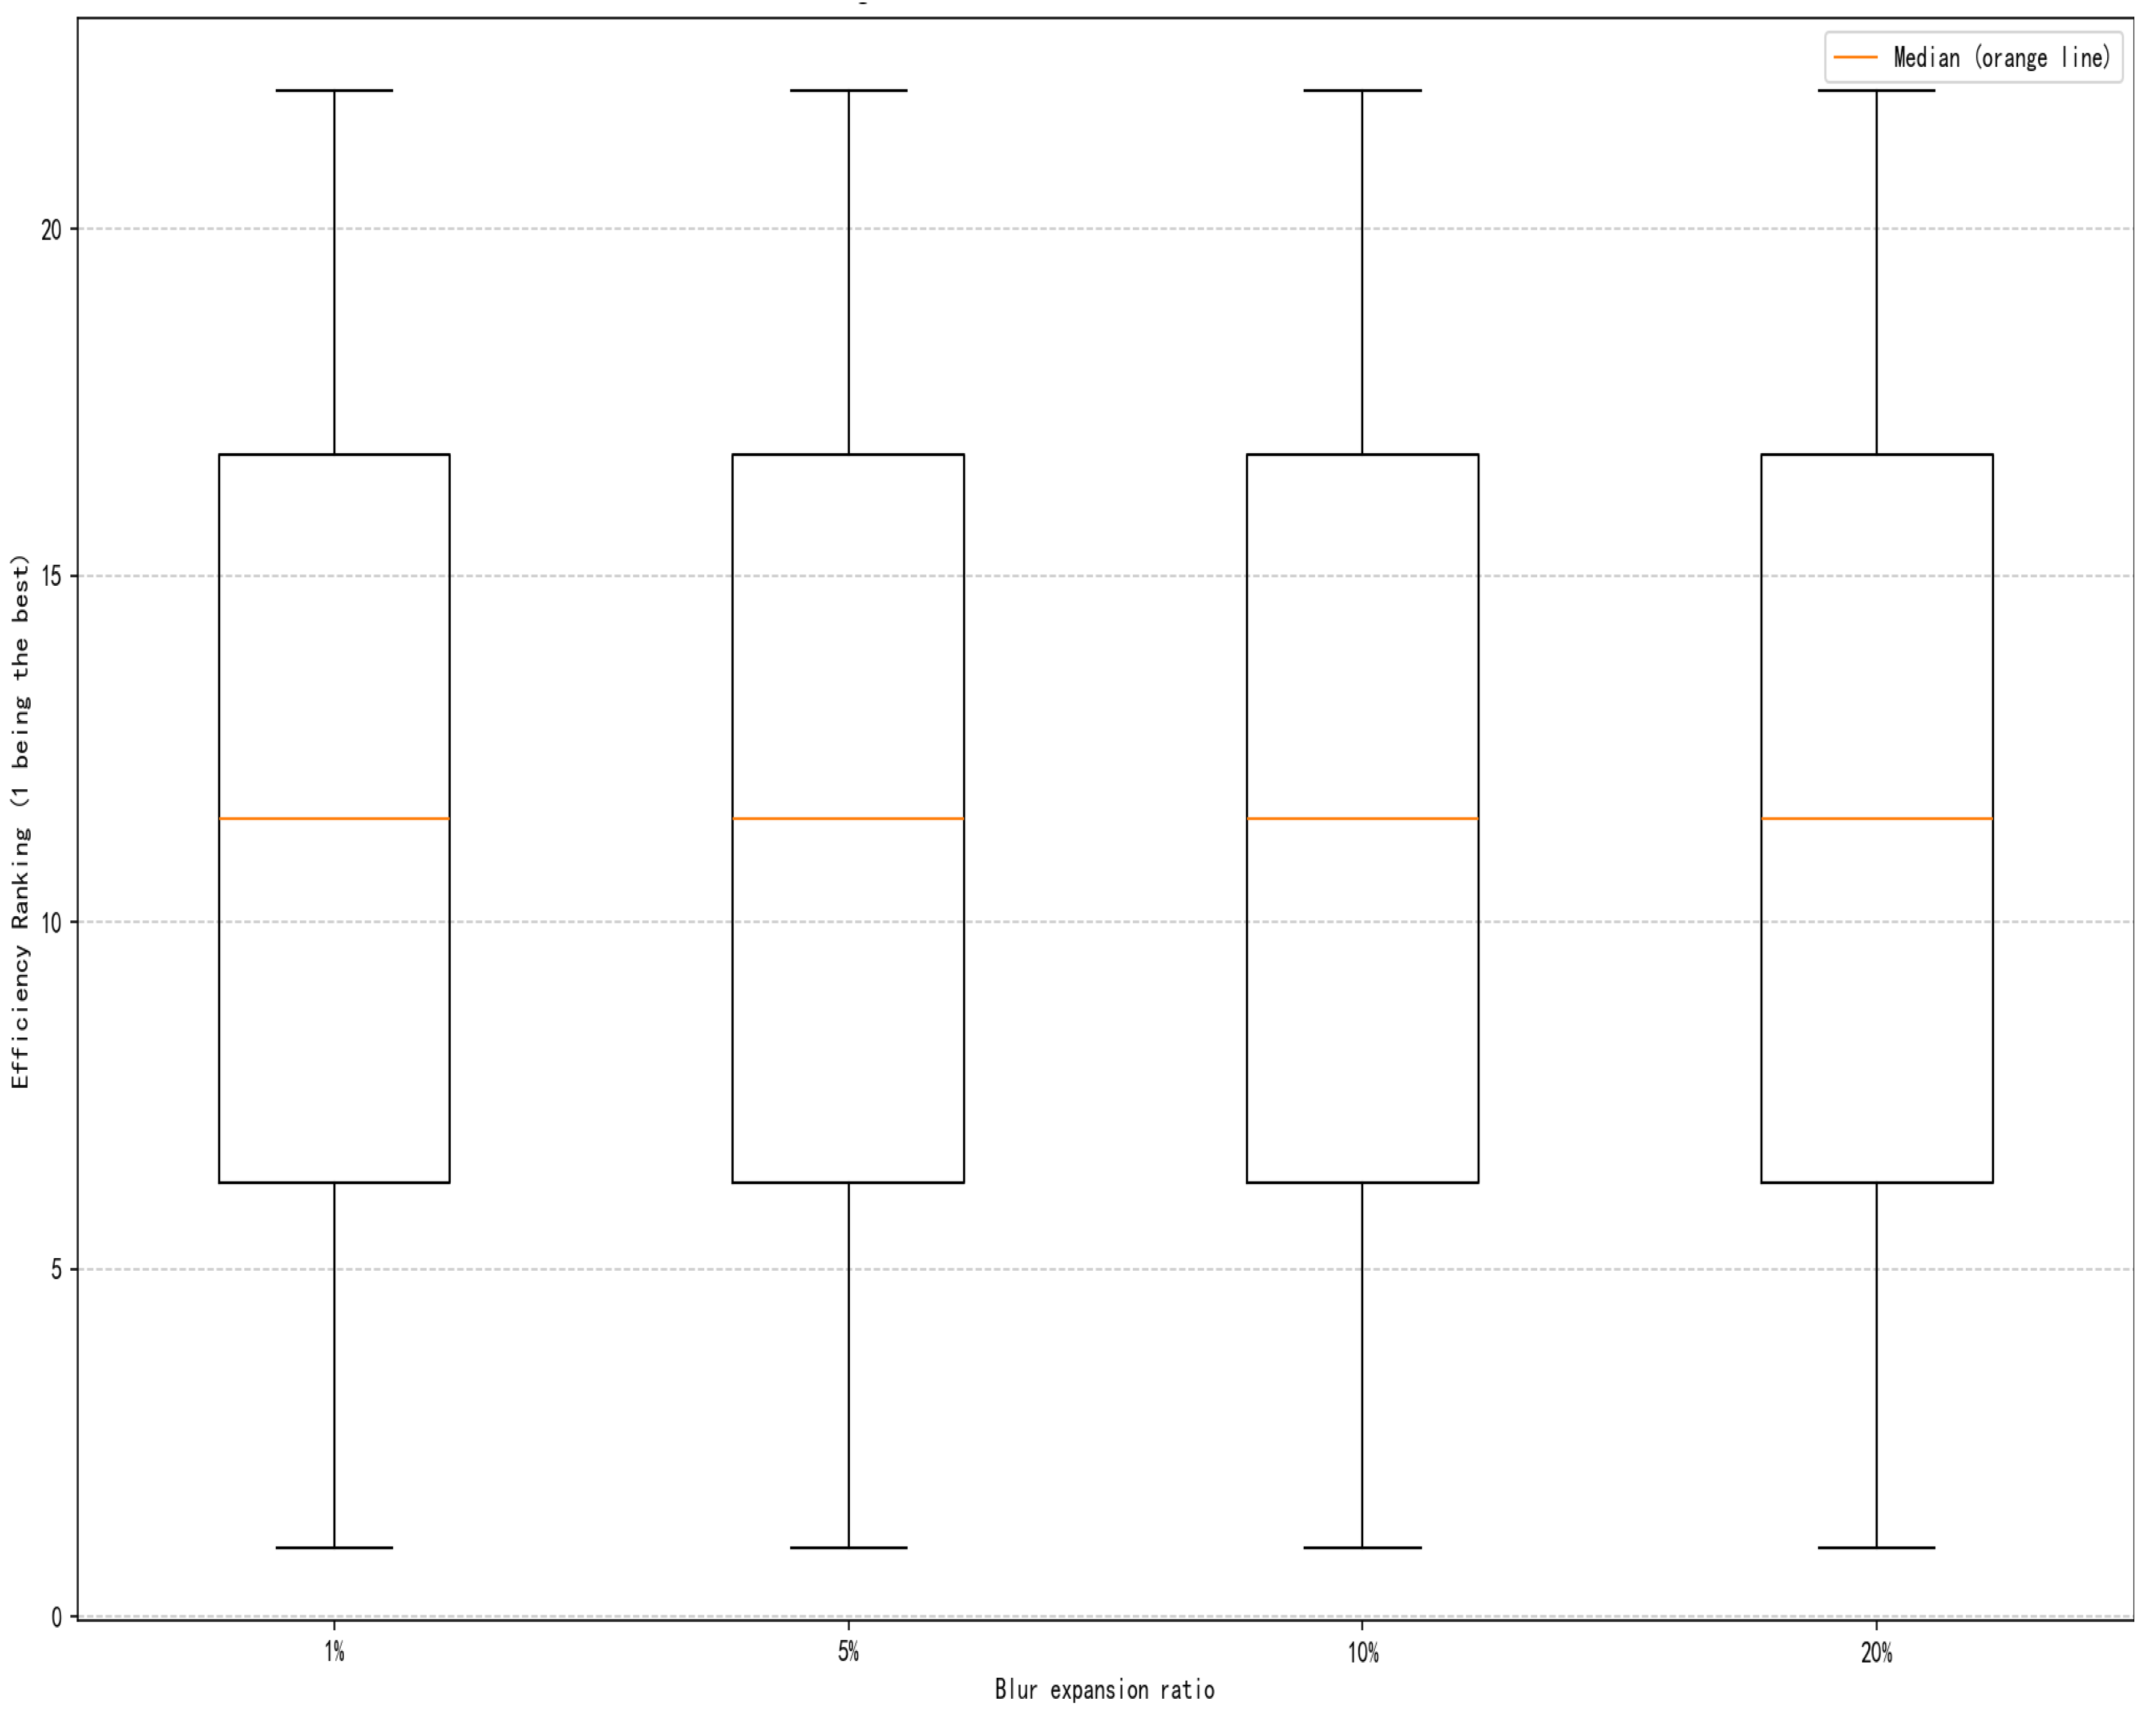
As shown in Figure 1, the impact of the fuzzy expansion range (1–20%) on the results is negligible under this dataset and model configuration. Therefore, any ratio (such as 1% or 5%) can be selected as the fuzzy margin, and the model exhibits good robustness. Therefore, this paper adopts an expansion ratio of 1%.
Figure 1.
Ranking distribution at different fuzziness ratios.
5.2. Testing of Different Parameters
To verify that the fuzzy stochastic DEA model proposed in this study possesses inherent robustness with respect to parameter selection, we present three sets of values: (0.10, 0.3), (0.05, 0.5) and (0.01, 0.7). These correspond to high-, medium-, and low-risk preferences, respectively. Substituting into Equation (15) yields Table 4.
Table 4.
The rankings of each DMU calculated using Equation (15) of different parameters .
By performing a Spearman’s rank correlation test on Table 4, we can obtain the Spearman’s rank correlation coefficient matrix, as shown in Table 5.
Table 5.
Spearman’s rank correlation of different parameters .
The Spearman’s correlation coefficient should be very close to 1.0, indicating a high degree of consistency in the rankings across the three sets of parameters. This suggests a highly significant positive correlation among the rankings, thereby demonstrating that the model exhibits a high degree of robustness in its selection of parameter .
5.3. Comparison of the Proposed Model with the Classical DEA
5.3.1. Determine DMU Weights Using a Factor Analysis Model
By applying the factor-analysis-based weighting model developed in Section 3 to the data in Table 2, we obtain the values in Table 6, Table 7 and Table 8.
Table 6.
Cumulative contribution rate.
Table 7.
Gray factor loading (rotated by varimax normalized).
Table 8.
Common degree and gray uniqueness.
After applying the variance-maximizing rotation, the factor loading matrix simplifies the factor structure, ensuring each variable exhibits high loadings on as few factors as possible to enhance interpretability. As shown in the table, variable a exhibits loading of 0.9935 on input factor 3, indicating that is primarily explained by input factor 3. Similarly, variables , , , , , and are, respectively, explained by input factor 1, input factor 1, input factor 2, output factor 3, output factor 1, output factor 2, and output factor 1.
Since the commonality of the load matrix remains unchanged after rotation, Table 8 is obtained. As shown in Table 8, the commonality of is as high as 0.9986, indicating that it is almost entirely explained by the factor, with a uniqueness of only 0.0014. The commonality of and is 0.7988 and 0.7936, respectively, indicating that approximately 80% of the variance is explained by the factors, with about 20% remaining as unique components. Similarly, , and exhibit high levels of explanation. The explanatory power of and is comparable to that of and .
Table 9 is obtained through steps 9 and 10 in Section 3. As shown in Table 9, the top three enterprises by weight are enterprise 10, enterprise 18, and enterprise 21. This indicates their superior input–output ratios, hence the higher weights assigned. The bottom three enterprises are enterprise 13, enterprise 20, and enterprise 4, demonstrating relatively poor input–output efficiency for these three entities. And Table 9 provides the CPF values for each DMU; then, Equation (13) can be used to calculate the weights for each DMU.
Table 9.
Comprehensive score coefficients and weight values for each enterprise.
5.3.2. Determining the Rankings of DMUs
By applying model (15) to the data in Table 2, based on the analysis in Section 5.2, the parameters (, ) take the values (0.05, 0.5). And the deterministic efficiency and fuzzy stochastic efficiency rankings of unweighted DMUs, as well as the weighted fuzzy stochastic rankings can be obtained, as shown in Table 10 and Table 11.
Table 10.
Classic DEA rankings and fuzzy random ranking.
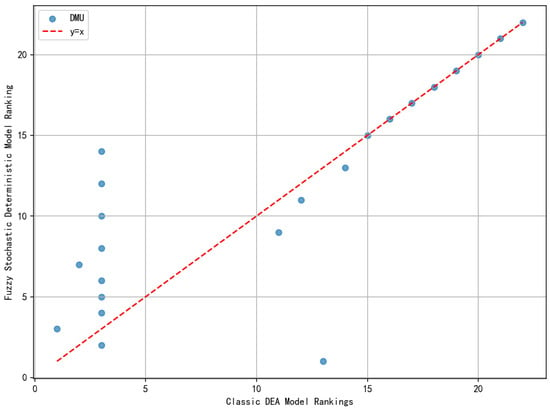
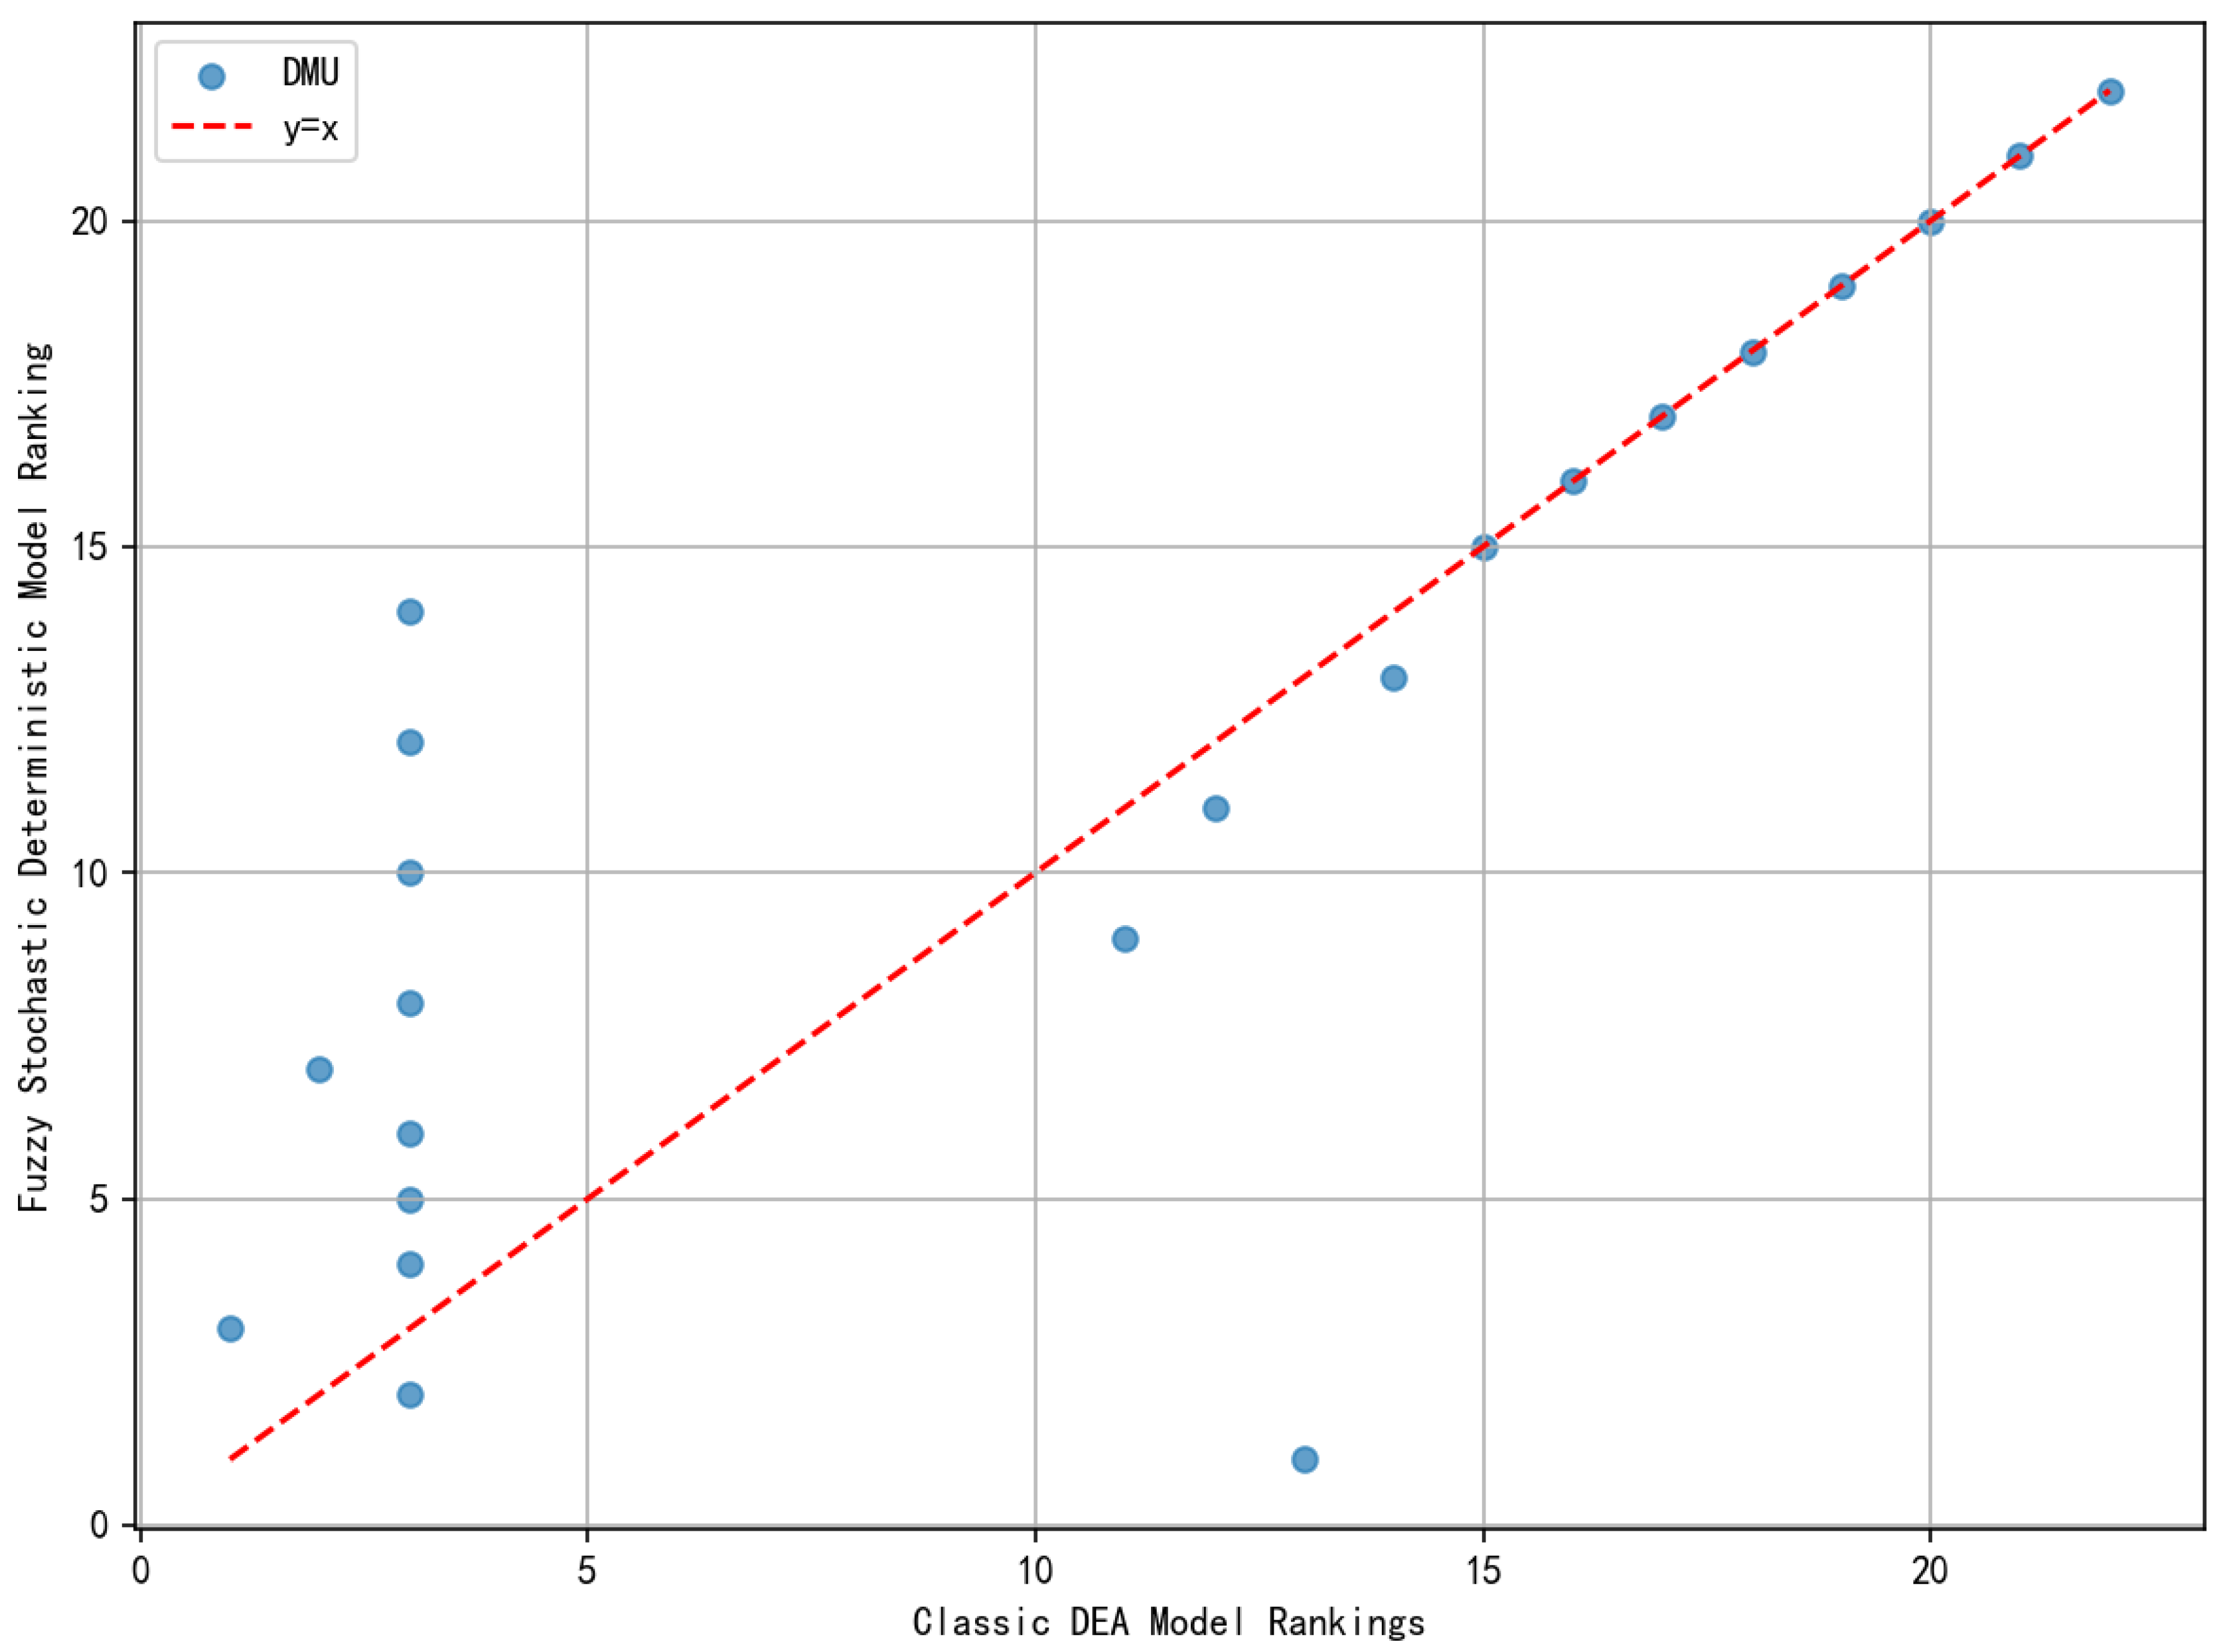
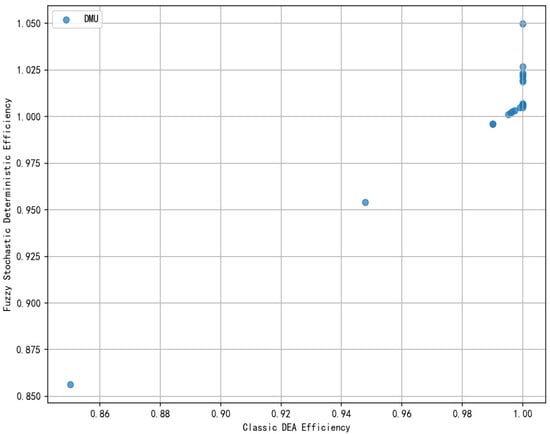
First, analyzing Table 10, from the perspective of efficiency value distribution, the mean efficiency value under the classical DEA model is 0.989 with a standard deviation of 0.032; under the fuzzy stochastic model, the mean efficiency value is 1.002 with a standard deviation of 0.036. The correlation coefficient of efficiency values between the two models is as high as 0.955, indicating a high degree of consistency in the overall trend. However, after accounting for data uncertainty, the fuzzy stochastic model shows a slight overall increase in efficiency values (mean increase of 0.012) and a slight increase in volatility. It is worth noting that under the deterministic model, a total of 15 DMUs achieve an efficiency value of 1 (efficient units), whereas under the fuzzy stochastic deterministic model, all DMUs have efficiency values greater than 0.85, but only some DMUs exceed 1 (as the model specification allows for efficiency values greater than 1). This reflects the adjustment effect of the fuzzy stochastic deterministic model on the efficiency frontier when dealing with uncertainty. The rankings of the two models show significant differences. Taking as an example, it ranks 13th under the classical DEA model but jumps to 1st under the fuzzy stochastic deterministic model, indicating that its relative efficiency advantage is significantly enhanced after considering uncertainty. In contrast, drops from third under the deterministic model to second under the fuzzy stochastic deterministic model, though its efficiency value remains high (1.027). From the perspective of ranking differences, units such as , , , exhibit substantial ranking changes, reflecting the high sensitivity of these DMUs’ efficiency evaluations to data uncertainty. Notably, and are both efficient units (efficiency value = 1) under the classical DEA model, but their rankings drop to 14th and 5th, respectively, under the fuzzy stochastic deterministic model, indicating that their efficiency advantages are difficult to maintain in an uncertain environment.
Next, analyzing Table 10, the weight coefficients in Table 9 reflect the importance of each DMU in the input–output structure, and the weight distribution exhibits a significant imbalance. (weight 0.117), (weight 0.107), and (weight 0.071) rank among the top three in terms of weight, indicating that these units have better input–output structures. In contrast, (weight 0.004), (weight 0.007), and (weight 0.016) have lower weights, indicating that their input–output structures are less ideal. From and , it can be observed that although they have the same fuzzy stochastic efficiency value, due to the influence of the input–output structure, ranks higher than after complete ranking. The efficiency scores and rankings of the weighted DMUs are shown in Table 11.
Table 11.
Weighted efficiency of the input–output structure.
ranks first in fuzzy stochastic efficiency, but because its weight is only 0.059 (ranked 9th), its comprehensive ranking drops to 4th. ranks 2nd in efficiency, but has the lowest weight (0.007), and its comprehensive ranking falls to 21st. This phenomenon reveals the inherent contradiction between efficiency evaluation and importance evaluation: high-efficiency units, if lacking sufficient importance, struggle to gain due recognition in a comprehensive system. From the perspective of the relationship between weight and efficiency, units such as are at moderate levels in both efficiency and weight, and their adjusted rankings are generally consistent with their efficiency rankings. For units such as , although their efficiency values are high, due to relatively low weights, their adjusted rankings are significantly lower than their efficiency rankings. This phenomenon indicates that the adjusted ranking results from the combined effect of both efficiency and input–output structure.
In this fuzzy random DEA model, fuzziness is used solely to adjust the possible value centers of the input-output data (i.e., the kernels of the fuzzy numbers) without altering the variance parameters of the random error terms. Therefore, when fuzziness primarily stems from systematic errors in measurement equipment (such as a fixed offset caused by uncalibrated instruments) and randomness arises from random fluctuations unrelated to that offset (such as environmental noise or reading errors), the fuzzy perception of the offset is independent of random variation. In this case, it is logical that fuzziness affects only the mean while the variance remains unchanged. Therefore, an improvement in the ranking of decision-making units (DMUs) under fuzzy conditions indicates that they have fewer systematic biases. The fact that ranks highly in terms of fuzzy random efficiency indicates that its systematic bias is small. However, when the input–output structure is taken into account, its ranking drops somewhat.
Figure 2 shows the distribution of ranking differences between the two models. It can be observed that the ranking differences are concentrated near 0 and extend to the right, indicating that the overall ranking exhibits a stable upward trend.
Figure 2.
Comparison of DMU rankings under the two models.
Figure 3 shows that the efficiency scores of both models are concentrated around 1. The classic DEA model exhibits frequent duplications at the efficiency value of 1, whereas the fuzzy stochastic deterministic model shows no such duplication of efficiency values. Thus, the distributions of efficiency scores of the two models are relatively consistent; however, the duplication rate of efficiency values in the fuzzy stochastic deterministic model is significantly lower than that in the classic DEA model.
Figure 3.
Comparison of efficiency values.
Through the above comparative analysis, the following management insights can be obtained: First, the comprehensive evaluation system should balance efficiency and importance. Relying solely on efficiency rankings may overlook differences in the importance of units, while overemphasizing weights may weaken the motivation for efficiency improvement. It is recommended to establish a dynamic weight adjustment mechanism that moderately favors high-efficiency units while maintaining evaluation stability. Second, attention should be paid to sensitivity analysis of ranking changes. For units with significant ranking fluctuations, such as , further analysis of the quality and stability of their input–output data should be conducted to identify key factors causing uncertainty in efficiency evaluation. Third, differentiated development strategies should be formulated. For units with high efficiency and high importance, advantages should be consolidated and support strengthened; for units with high efficiency but low importance, their importance should be reassessed or their strategic positioning enhanced; for units with low efficiency but high importance, improvement resources should be prioritized; and for units with low efficiency and low importance, resource optimization and restructuring or strategic adjustments should be considered.
5.4. Comparison of Efficiency Rankings Across Different DEA Models
To comprehensively evaluate the performance of the proposed fuzzy stochastic DEA model under conditions of uncertainty, this paper selects six representative DEA variants and one MCDM ranking model for comparative analysis. These include: the classical DEA model, the super-efficiency DEA model, the cross-efficiency DEA model, the ideal cell DEA model, and the DEA-MCDM composite ranking. All models adopt an output-oriented approach and the variable returns to scale (VRS) assumption to maintain consistency with the main model. By calculating the rankings of the DMUs across the various models, we can obtain Table 6.
As shown in Table 12, there are 7 DMUs ranked third in the super-efficiency DEA ranking. With the exception of the fuzzy stochastic model, cross-efficiency model and the DEA-MCDM model, all other models exhibited duplicate rankings. In contrast to the cross-efficiency model, the model proposed in this study provides insights into the input-output structure of DMUs. Here, DEA-MCDM integrates the efficiency information from all other models and uses the TOPSIS method to generate a ranking, thereby eliminating duplicate rankings.
Table 12.
Comparison of rankings across different DEA models.
Therefore, it can be said that, in terms of reducing ranking redundancy, the fuzzy stochastic DEA model, which takes into account the cost–benefit structure, offers significant advantages. And the proposed model derives efficiency rankings by incorporating input–output structures into a fuzzy stochastic DEA model, resulting in rankings that are more objective and reasonable.
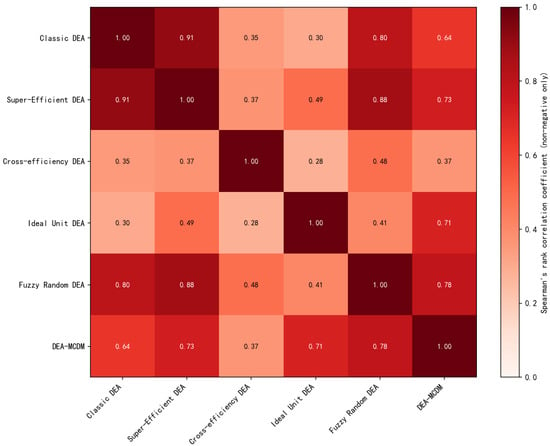
The correlation analysis among the rankings derived from different DEA models was further conducted using Spearman’s rank correlation coefficient, with the results presented in Figure 4. As can be seen from Figure 4, strong positive correlations are observed between classic DEA and super-efficiency DEA (0.91), classic DEA and fuzzy stochastic DEA (0.82), as well as between super-efficiency DEA and fuzzy stochastic DEA (0.88). This indicates a high degree of consistency in DMU rankings among these three models. The DEA-MCDM composite ranking shows correlations ranging from 0.25 to 0.1 with each individual model, suggesting that it effectively integrates ranking information from multiple DEA models.
Figure 4.
Heatmap of Spearman’s rank correlation coefficients for model rankings.
The lowest correlation is found between cross-efficiency DEA and ideal unit DEA (0.19). However, ideal unit DEA has relatively low correlations with classic DEA (0.30), cross-efficiency DEA (0.19) and fuzzy stochastic DEA (0.40), indicating that the introduction of an ideal DMU substantially alters the reference frontier, thereby leading to a ranking outcome different from that of these DEA models.
The aforementioned correlation differences reflect the distinct mechanisms by which each model handles uncertainty or weight non-uniqueness. The high degree of ranking consistency among Classic DEA, super-efficiency DEA, cross-efficient DEA and fuzzy stochastic DEA demonstrates that the proposed fuzzy stochastic DEA model not only preserves the original efficiency structure but also effectively discriminates between efficient DMUs and accounts for hybrid uncertainty. In summary, the validity of the rankings of the proposed models is confirmed through the analysis of Spearman’s rank correlation coefficients for model rankings.
6. Conclusions and Future Directions
Based on constructing a fuzzy stochastic deterministic DEA model with an extended exponential distribution, this paper introduces the input–output ratio of DMUs as the weight of DMUs, making the ranking of DMUs more comprehensive and objective. Technically, it also achieves a lower degree of efficiency overlap among DMU units. After avoiding the issue of sensitivity to extreme data caused by introducing super-efficiency models, it accomplishes effective complete ranking from another perspective. The fuzzy stochastic deterministic DEA model constructed in this paper is mainly realized through Lemma 1. Unlike necessity measures, possibility measures reflect the optimistic attitude of managers, which is more consistent with managerial mindsets. Finally, through the comparative experiment in Section 5 and the analysis of the figures, the significant effectiveness of this model in achieving complete ranking of DMUs is profoundly and intuitively demonstrated.
This paper assumes that fuzziness affects only the mean but not the variance, and that the probability density function and cumulative distribution function remain largely unaffected by fuzziness. Although this assumption is strong, it is justified and practically valuable in the following contexts:
- (1)
- When fuzziness primarily originates from systematic biases in measurement equipment (e.g., fixed offsets due to uncalibrated instruments), while randomness stems from stochastic fluctuations that are independent of such offsets (e.g., environmental noise, reading errors), as, in this case, the fuzzy perception of the offset is independent of the random variability; so, it is natural that fuzziness affects only the mean, leaving the variance unchanged.
- (2)
- In the absence of precise data, experts often provide judgments such as “approximately between a and b”. If the expert believes that the dispersion (i.e., variance) of the data is known and stable, and only the central value is uncertain, then it is appropriate to use fuzzy numbers to characterize the possible range of the central value. For example, the dimensional variation in products on a production line (variance) is determined by equipment precision, whereas the batch-to-batch average dimension may change fuzzily due to tool wear.
However, in the following situations, ignoring the effect of fuzziness on variance or distributional shape may lead to serious biases.
If fuzziness actually reflects insufficient knowledge about the parameters of a random distribution (e.g., scale parameters), then fuzziness should affect both the mean and the variance. For instance, when an expert states that “the error of this machine is approximately between 1% and 3%”, this statement may refer to either a mean shift or a change in the range of fluctuation. In such cases, assuming that the variance is unchanged will underestimate the total uncertainty.
Due to time constraints, future research can expand the theoretical scope by incorporating the influence of decision-makers’ psychology on decision-making, selecting different fuzzy deterministic models, and extending to new distributions to construct new fuzzy random variables. Additionally, as this study is limited by data collection, future work may consider the application of the model to large samples, integrating big data analysis techniques and deep learning.
Author Contributions
Conceptualization, L.D.; Methodology, L.D.; Validation, L.D.; Formal analysis, L.D.; Investigation, L.D.; Supervision, C.L. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Data Availability Statement
Due to privacy restrictions, the data presented in this study are available upon request from the authors.
Conflicts of Interest
The authors declare no conflict of interest.
References
- Charnes, A.; Cooper, W.W.; Rhodes, E. Measuring the efficiency of decision making units. Eur. J. Oper. Res. 1978, 2, 429–444. [Google Scholar] [CrossRef] [Scilit]
- Hatami-Marbini, A.; Emrouznejad, A.; Tavana, M. A taxonomy and review of the fuzzy data envelopment analysis literature: Two decades in the making. Eur. J. Oper. Res. 2011, 214, 457–472. [Google Scholar] [CrossRef] [Scilit]
- Olesen, O.B.; Petersen, N.C. Stochastic data envelopment analysis—A review. Eur. J. Oper. Res. 2016, 251, 2–21. [Google Scholar] [CrossRef] [Scilit]
- Peykani, P.; Mohammadi, E.; Saen, R.F.; Sadjadi, S.J.; Rostamy-Malkhalifeh, M. Data envelopment analysis and robust optimization: A review. Expert Syst. 2020, 37, e12534. [Google Scholar] [CrossRef] [Scilit]
- Kao, C.; Liu, S.T. Fuzzy efficiency measures in data envelopment analysis. Fuzzy Sets Syst. 2000, 113, 427–437. [Google Scholar] [CrossRef] [Scilit]
- Jahanshahloo, G.R.; Lotfi, F.H.; Shahverdi, R.; Adabitabar, M.; Rostamy-Malkhalifeh, M.; Sohraiee, S. Ranking DMUs by l1-norm with fuzzy data in DEA. Chaos Solitons Fractals 2009, 39, 2294–2302. [Google Scholar] [CrossRef] [Scilit]
- Luhaniwal, J.; Agarwal, S.; Mathur, T. An integrated DEA-fuzzy AHP method for prioritization of renewable energy sources in India. Sci. Rep. 2025, 15, 838. [Google Scholar] [CrossRef] [Scilit]
- Cooper, W.W.; Deng, H.; Huang, Z.; Li, S.X. Chance constrained programming approaches to congestion in stochastic data envelopment analysis. Eur. J. Oper. Res. 2004, 155, 487–501. [Google Scholar] [CrossRef] [Scilit]
- Abdolazimi, O.; Sepehrifar, M.; Shishebori, D.; Banicescu, I.; Azad, S.; Pishini, K.; Ma, J. A stochastic DEA-GARMA integration for dynamic forecasting of undesirable outputs applied to the temporal efficiency analysis of water and sewerage services. J. Clean. Prod. 2025, 521, 146177. [Google Scholar] [CrossRef] [Scilit]
- Arabmaldar, A.; Hatami-Marbini, A.; Loske, D.; Hammerschmidt, M.; Klumpp, M. Robust data envelopment analysis with variable budgeted uncertainty. Eur. J. Oper. Res. 2024, 315, 626–641. [Google Scholar] [CrossRef] [Scilit]
- Peykani, P.; Mohammadi, E.; Emrouznejad, A.; Pishvaee, M.S.; Rostamy-Malkhalifeh, M. Fuzzy data envelopment analysis: An adjustable approach. Expert Syst. Appl. 2019, 136, 439–452. [Google Scholar] [CrossRef] [Scilit]
- Omrani, H.; Alizadeh, A.; Emrouznejad, A.; Teplova, T. A robust credibility DEA model with fuzzy perturbation degree: An application to hospitals performance. Expert Syst. Appl. 2022, 189, 116021. [Google Scholar] [CrossRef] [Scilit]
- Özçalici, M.; Pamucar, D.; Gurler, H.E.; Karyağdi, N.G.; Kaya, A. A Robust Hybrid MCDM Framework with Emphasis on Decision Stability Intervals: Performance Evaluation of Global Insurance Brokers Using Fuzzy LBWA and Modified ARTASI. Appl. Soft Comput. 2026, 190, 114557. [Google Scholar] [CrossRef] [Scilit]
- Wang, Y.; Wei, H.; Wen, J.; He, J.; Li, P. Assessing organizational vulnerability of nuclear power plants using AHP-fuzzy sets method. Ann. Nucl. Energy 2025, 211, 110896. [Google Scholar] [CrossRef] [Scilit]
- Andersen, P.; Petersen, N.C. A procedure for ranking efficient units in data envelopment analysis. Manag. Sci. 1993, 39, 1261–1264. [Google Scholar] [CrossRef] [Scilit]
- Zhu, J. Super-efficiency and DEA sensitivity analysis. Eur. J. Oper. Res. 2001, 129, 443–455. [Google Scholar] [CrossRef] [Scilit]
- Mehrabian, S.; Alirezaee, M.R.; Jahanshahloo, G.R. A complete efficiency ranking of decision making units in data envelopment analysis. Comput. Optim. Appl. 1999, 14, 261–266. [Google Scholar] [CrossRef] [Scilit]
- Doyle, J.; Green, R. Efficiency and cross-efficiency in DEA: Derivations, meanings and uses. J. Oper. Res. Soc. 1994, 45, 567–578. [Google Scholar] [CrossRef]
- Wu, J.; Sun, J.; Liang, L. Cross efficiency evaluation method based on weight-balanced data envelopment analysis model. Comput. Ind. Eng. 2012, 63, 513–519. [Google Scholar] [CrossRef] [Scilit]
- Liang, L.; Wu, J.; Cook, W.D.; Zhu, J. Alternative secondary goals in DEA cross-efficiency evaluation. Int. J. Prod. Econ. 2008, 113, 1025–1030. [Google Scholar] [CrossRef] [Scilit]
- Seiford, L.M.; Zhu, J. Context-dependent data envelopment analysis—Measuring attractiveness and progress. Omega 2003, 31, 397–408. [Google Scholar] [CrossRef] [Scilit]
- Wang, Y.M.; Luo, Y. DEA efficiency assessment using ideal and anti-ideal decision making units. Appl. Math. Comput. 2006, 173, 902–915. [Google Scholar] [CrossRef] [Scilit]
- Tavana, M.; Khalili-Damghani, K.; Rahmatian, R. A hybrid fuzzy MCDM method for measuring the performance of publicly held pharmaceutical companies. Ann. Oper. Res. 2015, 226, 589–621. [Google Scholar] [CrossRef] [Scilit]
- Kehinde, T.O.; Chung, S.H.; Olanrewaju, O.A. An integrated approach to stock selection and ranking: Combining Shannon entropy technique, DEA, and inverse DEA. IEEE Access 2025, 13, 138851–138866. [Google Scholar] [CrossRef] [Scilit]
- Shannon, C.E. A mathematical theory of communication. Bell Syst. Tech. J. 1948, 27, 379–423. [Google Scholar] [CrossRef] [Scilit]
- Jahanshahloo, G.R.; Lotfi, F.H.; Izadikhah, M. Extension of the TOPSIS method for decision-making problems with fuzzy data. Appl. Math. Comput. 2006, 181, 1544–1551. [Google Scholar] [CrossRef] [Scilit]
- Lei, X.; Qiu, W.; Li, J.; Dai, Q. Robust performance evaluation and improvement: Opening the black-box of weight space. Omega 2025, 138, 103409. [Google Scholar] [CrossRef] [Scilit]
- Zadeh, L.A. Fuzzy sets as a basis for a theory of possibility. Fuzzy Sets Syst. 1978, 1, 3–28. [Google Scholar] [CrossRef] [Scilit]
- Bustince, H.; Barrenechea, E.; Pagola, M.; Fernandez, J.; Xu, Z.; Bedregal, B.; Montero, J.; Hagras, H.; Herrera, F.; De Baets, B. A historical account of types of fuzzy sets and their relationships. IEEE Trans. Fuzzy Syst. 2015, 24, 179–194. [Google Scholar] [CrossRef] [Scilit]
- Ebrahimnejad, A.; Tavana, M.; Nasseri, S.H.; Gholami, O. A new method for solving dual DEA problems with fuzzy stochastic data. Int. J. Inf. Technol. Decis. Mak. 2019, 18, 147–170. [Google Scholar] [CrossRef] [Scilit]
- Johnson, R.A.; Wichern, D.W. Applied Multivariate Statistical Analysis; Prentice Hall: Hoboken, NJ, USA, 2002. [Google Scholar]
- Bartlett, M.S. The statistical conception of mental factors. Br. J. Psychol. 1937, 28, 97. [Google Scholar] [CrossRef] [Scilit]
- Kaiser, H.F. The varimax criterion for analytic rotation in factor analysis. Psychometrika 1958, 23, 187–200. [Google Scholar] [CrossRef] [Scilit]
- Huang, M.; Xia, T.; Chen, Z.; Pan, E.; Xi, L. A DEA integrated grey factor analysis approach for efficiency evaluation and ranking in uncertain systems. Comput. Ind. Eng. 2021, 162, 107681. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.