


Abstract
General Matrix Multiplication (GEMM) is a fundamental computational kernel in scientific computing, serving as the foundation for numerous complex tasks. However, in practical applications, the performance of GEMM is often constrained by irregular matrix dimensions and the diversity of hardware architectures. In particular, when processing small and irregular matrices, GEMM typically exhibits reduced computational efficiency. To address these challenges, this paper proposes a GEMM acceleration method based on an adaptive core grouping strategy. The method consists of two key components: a core grouping mechanism that alleviates workload imbalance among multi-core CPUs, and an adaptive block partitioning algorithm that dynamically selects optimal tiling schemes according to the matrix dimensions, achieving both load balance and cache-friendly data access. Experimental results on the Kunpeng CPU platform demonstrate that the proposed method achieves significant performance improvements compared to the Kunpeng KML math library, reaching a peak acceleration of up to 2.1× and an average speedup of 1.64×. These results validate the effectiveness and efficiency of the proposed approach in handling small and irregular matrix computation scenarios.
1. Introduction
General Matrix-Matrix Multiplication (GEMM) is one of the most fundamental computational kernels in scientific computing and is widely regarded as the “cornerstone of computing power” that underpins numerous complex applications. Its importance is reflected in both scientific research and engineering practice. In High-Performance Computing (HPC) [1], widely used benchmarks such as HPL [2] and HPCC [3] indicate that GEMM operations account for more than 90% of the total workload [4,5,6]. Consequently, the efficiency of GEMM implementations directly affects the achievable performance of modern supercomputing systems. In large-scale scientific computing scenarios, ranging from Computational Fluid Dynamics (CFD) [7,8] to Quantum Chemistry [9], GEMM frequently becomes a performance-critical component due to its high computational intensity and extensive resource requirements. Given the growing computational demand, researchers have explored both algorithmic and hardware-level strategies to accelerate GEMM.
Specialized hardware accelerators, such as analog in-memory computing (IMC), have been proposed to perform matrix operations directly within memory arrays, reducing data movement and alleviating the memory wall problem [10,11,12]. By exploiting the physical characteristics of emerging memory devices, IMC-based accelerators can achieve high energy efficiency and massive parallelism for linear algebra workloads. However, such accelerators often require specialized hardware and programming models, which limits their general applicability and makes optimization on widely deployed multi-core CPUs both practical and necessary.
Extensive efforts have been devoted to optimizing GEMM on conventional CPUs. Highly optimized linear algebra libraries, such as OpenBLAS [13], BLIS [14], and Arm Performance Libraries [15], achieve near-peak performance for large dense matrices on modern CPU architectures, including ARM platforms, by employing blocking, cache-aware optimizations, and vectorization techniques. Although these libraries perform well for large dense matrices, many real-world workloads involve small-scale or irregular matrices with unbalanced dimensions, irregular shapes, or sparsity [16]. Such matrices frequently arise in block matrix decomposition, iterative methods [17], local updates in multiscale simulations [18], and deep learning [19] pipelines such as im2col [20] transformations and attention mechanisms [21].
While GPUs are commonly used to accelerate dense linear algebra workloads, CPU-only execution remains important in many practical scenarios. Small and irregular matrix multiplications often appear in CPU-resident pipelines or latency-sensitive workloads, where frequent data transfers to a GPU can offset the benefits of offloading. Previous studies have demonstrated that offloading GEMM operations to GPUs can significantly improve performance for large-scale dense computations [22,23]; however, these gains may be limited for small or irregular matrices due to kernel launch overhead and fine-grained parallelism constraints. Optimizing CPU-only GEMM is therefore still necessary, particularly in scenarios such as edge inference devices [24], CPU-resident pre-and post-processing pipelines [25], or heterogeneous scheduling [26] where GPU resources are fully utilized. By improving CPU performance for small and irregular matrices, applications can maintain high efficiency without relying on discrete GPU accelerators.
Motivated by these observations, this work focuses on improving the efficiency of small and irregular GEMM operations on ARM-based multi-core processors. Our approach, AGP-GEMM (Adaptive Grouping and Partitioning GEMM), incorporates an adaptive core grouping strategy (ACG), which dynamically adjusts core grouping based on matrix size and available cores to achieve optimal load balancing. In addition, AGP-GEMM employs a block partition selection mechanism that generates optimized partitioning schemes according to the CPU memory hierarchy. This mechanism identifies the short and long dimensions of a matrix and applies tailored partitioning strategies. For example, in a 128 × 30,000 matrix, 128 is treated as the short dimension and 30,000 as the long dimension. Experimental results demonstrate that AGP-GEMM significantly improves GEMM performance for small and irregular matrices on the evaluated ARM platform. Based on this work, our main contributions are summarized as follows:
- It proposes an ACG mechanism to dynamically adjust the grouping of CPU cores according to the size of input matrices and the number of available cores, thereby achieving near-optimal load balancing on the CPU.
- Building on this, it presents a self-designed adaptive block partitioning mechanism that operates on top of the optimal ACG, generating the best block partitioning scheme for small and irregular matrices. This mechanism aims to enhance hardware utilization and maximize computational efficiency.
- Furthermore, it shows that the integration of ACG and adaptive block partitioning significantly improves the performance of GEMM on CPU, particularly for small and irregular matrices, as validated by comparisons with the original linear algebra libraries.
The rest of the paper is organized as follows. Section 2 discusses motivation, related work, and previous studies relevant to this article. Section 3 introduces background techniques, such as GEMM and commonly used optimization methods: partitioning, data packing, and kernel. It also explains the differences between GEMM and small, irregular matrices, as well as the working characteristics of CPUs. Section 4 provides a detailed description of the proposed method. This includes ACG grouping of cores based on matrices and selected cores, adaptive matrix partitioning after grouping, and a summary of both methods. Section 5 presents and assesses the experimental results. It covers the experimental setup, comparison methods, evaluation indicators, and detailed analysis of results. Section 6 concludes the article, including the overall summary and discussion of future work.
2. Motivation and Related Works
2.1. Motivation
With CPU architectures evolving towards increasingly multi-core designs [27,28], optimization strategies have mainly focused on partition scheduling [29], data packing [30,31], inter-core collaborative computation [32], and edge-node processing [33]. These techniques aim to unleash the full computational power of multi-core hardware. Even small-matrix computations show some performance benefits. However, these matrices often have limited sizes and irregular shapes. As a result, these strategies alone are not sufficient to fully exploit multi-core hardware.
As summarized in Table 1, GEMM workloads in Transformer [34] models are typically characterized by small sizes and highly irregular shapes, reflecting the structural diversity of both Feed-Forward Networks (FFNs) and Attention mechanisms. The GEMM sizes listed in Table 1 represent representative configurations derived from commonly reported Transformer hidden dimensions and FFN expansion ratios in publicly available model architectures, rather than exact values from specific implementations.
Table 1.
Representative GEMM Shapes Observed in Transformer Workloads. Sizes are derived from common FFN expansion ratios and hidden dimensions reported in publicly available Transformer architectures.
For small matrices (), GEMM shapes such as and are typical for lightweight Transformer models and early GPT-style architectures. Medium-sized GEMMs (), such as , often arise in larger-scale architectures including Switch-Transformer and other high-capacity Transformer variants. Even larger and more irregular shapes (), for example , may appear in very large models or Mixture-of-Experts (MoE) architectures where FFN expansion layers significantly increase intermediate matrix dimensions.
Beyond the representative configurations listed in Table 1, Transformer models frequently exhibit a wide variety of additional irregular GEMM shapes. Examples include matrices generated by FFN expansion layers, attention projections, and fused FFN–Attention operations. These GEMMs appear repeatedly in nearly every layer and token-processing step, forming the fundamental computational units of modern Transformer workloads. Consequently, efficient execution of such irregular GEMMs is critical for achieving high-performance training and inference.
2.2. Related Works
Small and irregular matrices are widely present in scenarios such as scientific computing, graph computing, and deep learning. They have a significant impact on overall computing performance. Due to their small scale and irregular shape, conventional large matrix optimization strategies are usually ineffective. Early research primarily focused on optimizing data packing and memory access, as demonstrated by Utrera et al. [30], Tandon [35], and Hestness [36]. Liu et al. [37] analyzed small-scale and irregular matrix multiplication on ARMv8 and proposed the EPPA algorithm, which reduces unnecessary packing and cache contention while integrating data prefetching to mitigate cache misses.
In addition, several widely used BLAS libraries provide optimized implementations for matrix multiplication with different design focuses. OpenBLAS [13] emphasizes multi-threaded execution and efficient parallel scheduling, making it suitable for general-purpose high-throughput workloads. LIBXSMM [38] targets small and medium-sized matrix multiplications by leveraging just-in-time (JIT) code generation to produce highly specialized kernels for fixed matrix sizes, which is particularly effective for repeated submatrix operations. Kunpeng Math Library (KML) [39] is the proprietary high-performance BLAS library optimized for Huawei Kunpeng CPUs. KML adopts multi-core parallel execution, cache-aware scheduling, and architecture-specific optimizations to maximize GEMM performance on ARMv8-based Kunpeng processors.
GPU acceleration and hybrid CPU–GPU computing have also been extensively explored to improve linear algebra performance, particularly for large-scale dense matrix operations. Andrade et al. [23] proposed the inq framework, which leverages GPU-accelerated BLAS (e.g., CUBLAS) to efficiently handle GEMM, including small-block multiplications arising in iterative eigensolvers. Similarly, Kartsev et al. [22] investigated hybrid CPU–GPU strategies for DFT workloads and demonstrated substantial performance gains when offloading large dense computations to GPUs. However, where frequent kernel launches, limited parallelism, and data transfer overhead between CPU and GPU can significantly reduce efficiency. As a result, for fine-grained, latency-sensitive, or CPU-resident workloads, CPU-based optimization remains essential and can be more effective in practice.
For the NUMA characteristics of ARMv8 multi-core platforms, researchers have proposed several architecture-aware optimization strategies to improve parallel efficiency. Zhang et al. [40] proposed a NUMA-aware method that optimizes DGEMM performance by reducing cross-node memory access events, leveraging two-level parallelism between and within nodes for task independence and data locality. Yu et al. [41] proposed a NUMA-aware SpMV optimization strategy on the Phytium 2000+ ARMv8 64-core processor. Zheng et al. [42] combined coarse-grained NUMA parallelism between nodes with a fine-grained, cache-aware strategy within nodes, improving overall parallel efficiency for sparse matrix multiplication.
3. Background
3.1. General Matrix-Matrix Multiplication
GEMM is a fundamental operation in linear algebra, mathematically defined as
where matrix A has dimensions , matrix B has dimensions , and matrix C has dimensions . Scalars and are coefficients that scale the product and the existing matrix C, respectively.
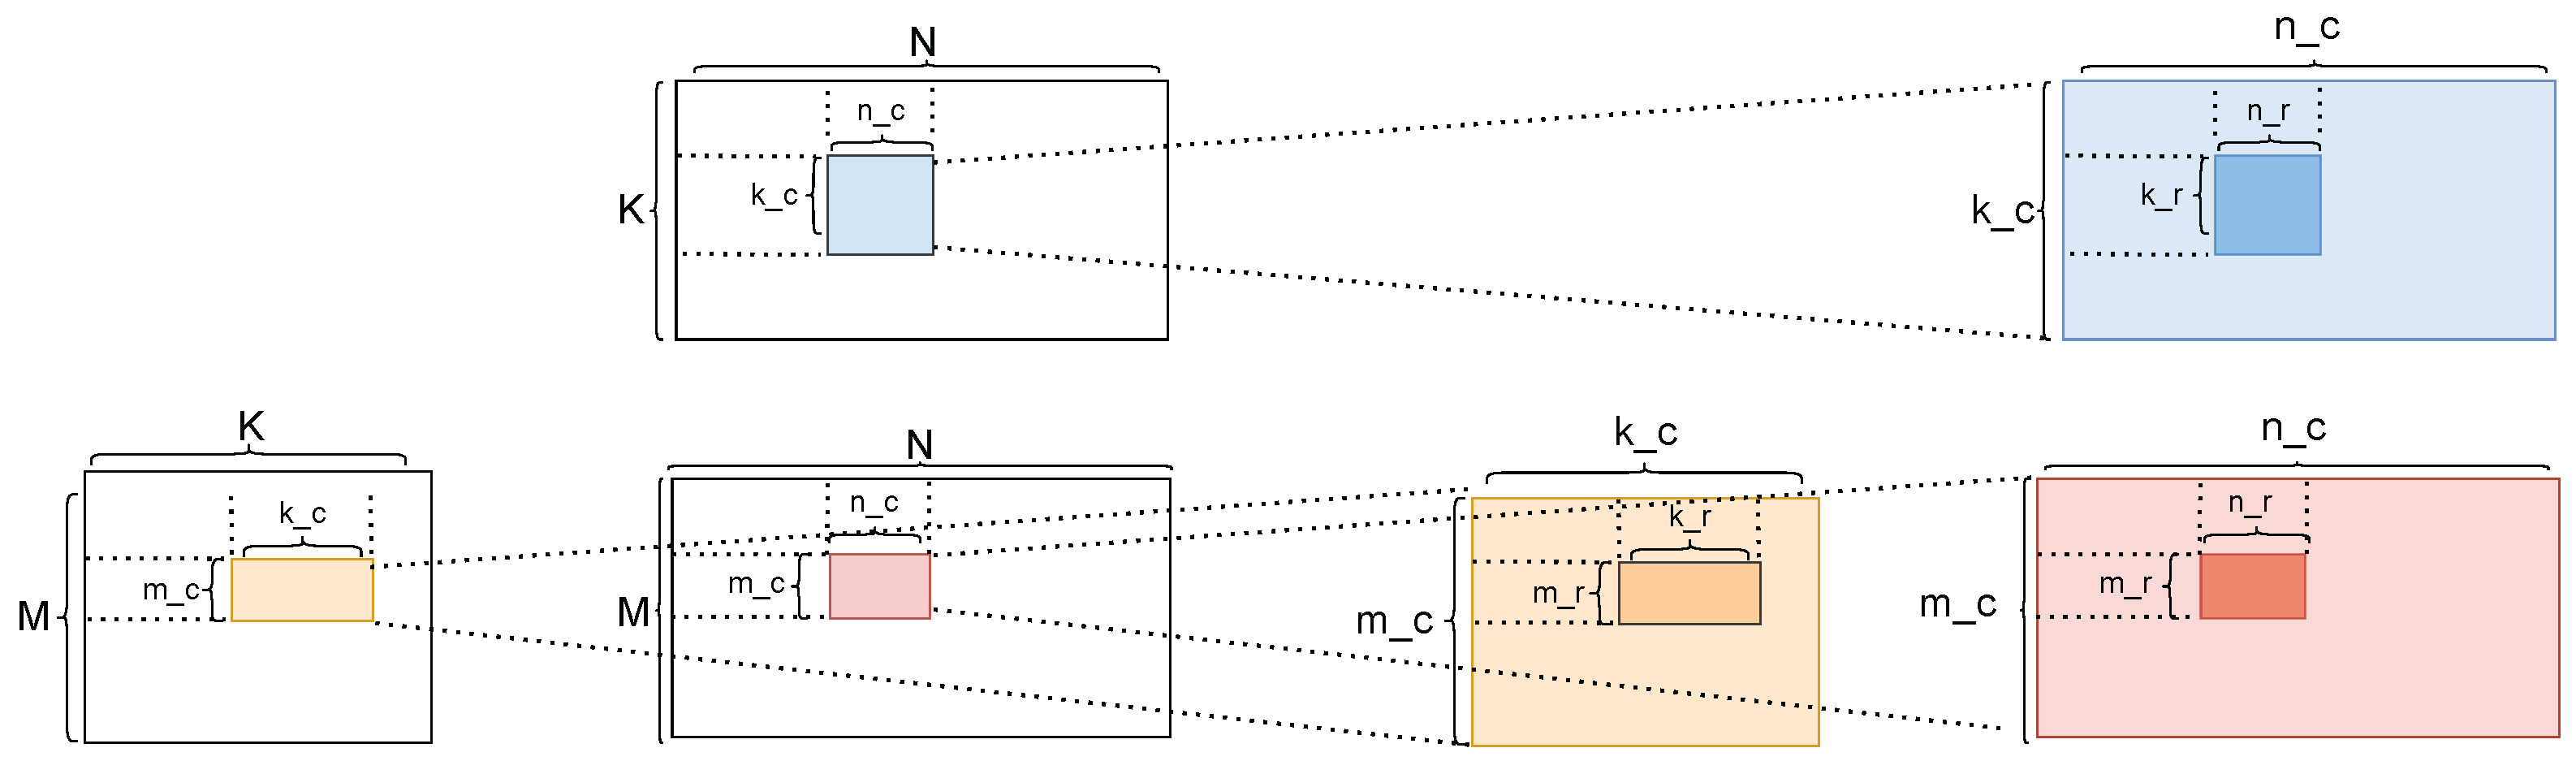
In CPU architectures, matrix multiplication is organized according to the hierarchical memory structure (main memory, cache, and registers), requiring layered blocking to match different access speeds and capacity constraints. First, the matrices are divided into large blocks of size and , ensuring that each block fits entirely into the cache and minimizing the need to fetch data from main memory. These cache-level blocks are then further subdivided into smaller sub-blocks of size and before computation, allowing the working data to reside completely within the registers. Through such hierarchical blocking, the CPU can effectively maximize register utilization and minimize memory access overhead, as illustrated in Figure 1.
Figure 1.
The classic implementation of GEMM.
3.2. Partitioning
In matrix multiplication , blocking (or tiling) is a fundamental optimization technique to fully utilize registers and multi-level caches. Given the matrix dimensions M, N, and K, block sizes , , and are chosen according to the hardware characteristics, ensuring that each block can reside in registers or high-speed cache for multiple reuse, thus reducing memory traffic.
The blocking procedure is as follows: matrix A is partitioned along the M and K dimensions into blocks of size ; matrix B is partitioned along K and N into blocks of size ; matrix C is correspondingly partitioned into blocks. The outer loops iterate over the blocks of C, performing accumulation operations for each block. The inner loops traverse the corresponding dimension blocks to multiply the A and B blocks and accumulate the results into the C block.
3.3. Packing
Packing is a complementary technique to blocking. It reorganizes submatrices into a hardware-friendly memory layout. After blocking, panels of A and B may not be stored in contiguous memory locations. To resolve this, the algorithm repacks the selected sub-blocks into temporary buffers and . In the outer loop, a panel of size from matrix A is packed into a contiguous buffer . This step ensures that subsequent accesses by the kernel can exploit cache-line alignment and prefetching. Similarly, in the next loop, sub-blocks of B with dimensions are packed into , which is sized to fit the cache. This repacking allows data to be accessed in a streaming manner, with minimal stride. As a result, cache conflicts are reduced, and spatial locality is improved.
3.4. Micro-Kernel
The micro-kernel is the innermost computational unit of GEMM. It performs multiply–accumulate operations on packed submatrices. After blocking and packing panels of size and , the micro-kernel further divides the packed data into register-level tiles of size . The values of and are chosen based on the SIMD width and register capacity. For each tile, a block of size from multiplies a corresponding block of size from . The partial results are accumulated into a register-resident block of C. Once the full dimension has been traversed, the computed block is written back to memory. This hierarchical mapping from to ensures efficient register usage, data reuse, and SIMD parallelism.
3.5. Small and Irregular Matrices
Small and irregular matrices typically refer to matrices whose sizes range from tens to a few hundred, and whose row and column dimensions are asymmetric or not evenly divisible. First, these matrices often have disproportionate row and column counts, making it difficult to align them with register or cache tiles of size or , respectively. Second, in GEMM and other matrix multiplication operations, matrices are typically blocked into fixed sizes (e.g., , ) to optimize cache and register utilization. However, when the matrix dimensions are not integer multiples of these block sizes, smaller submatrices form at the matrix boundaries. These submatrices remain small and irregular, making it hard to align them precisely with register tiles () or cache tiles (), thus forming what are called “small and irregular matrices, as illustrated in Figure 2.
Figure 2.
The causes of small and irregular matrices.
4. Overview
4.1. Core Grouping Strategy
This section introduces a core grouping optimization strategy to maximize the utilization of computing units and improve inter-core coordination. Multiple physical cores are bound together to form an independent computing group. Each group shares cache resources and task logic, enabling operation as a cooperative execution unit. The mechanism leverages the low-latency interconnect and shared cache of ARM-based architectures (e.g., Kunpeng). This approach enhances cooperative execution efficiency, especially in small-scale matrix computations.
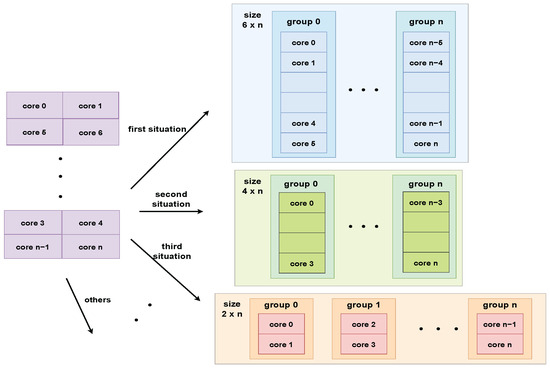
Assume the system contains a physical cores. These cores are divided into a number of groups that is always a multiple of 2 . The size of each group is determined by dividing a by the number of groups, so each group contains , and so on cores, depending on the grouping. For instance, if , organizing the system into 4 groups gives 8 cores per group; organizing into 8 groups gives 4 cores per group. This grouping is illustrated in Figure 3.
Figure 3.
Core Layouts under Different Group Sizes.
To further refine the grouping approach, during initialization, the system determines the optimal core grouping level based on the matrix size, workload granularity, and the number of available threads. Let M denote the matrix dimension along which the workload is partitioned, and let B represent the block size for a single computation. The total number of computation rounds along this dimension is then given by:
where R represents the number of M-dimensional blocks to be processed. Given a candidate set of group numbers , each grouping configuration divides the total cores C into g groups, with each group containing cores. To evaluate the efficiency of a particular grouping configuration, we define the intra-group task utilization as:
where indicates the fraction of fully utilized computation slots for the group, considering both full rounds and any partially filled rounds. The optimal grouping configuration is then chosen to maximize efficiency:
where is the optimal number of groups and is the number of cores per group.
Practical Determination of and
In practice, the selection of is not solely determined by Equation (3), but also influenced by matrix dimensions and hardware characteristics.
(1) Matrix dimensions. The parameter M determines the number of computation rounds R. When m is small, increasing g improves parallelism and reduces idle cores. When M is large, smaller g (larger groups) reduces synchronization overhead. The dimension N affects inter-group scalability: larger N enables better load balancing across groups.
(2) Cache constraint. The block size B and the derived should satisfy:
to ensure that each group operates within its cache capacity.
(3) NUMA locality. Groups are formed within the same NUMA node or cache cluster to minimize cross-node communication.
Each group is bound as an independent computational unit with its own task queue and dedicated cache space. Cores within the same group collaborate through the shared task queue, ensuring that all tasks assigned to the group execute on physically adjacent cores, thereby minimizing inter-cluster communication overhead and fully leveraging the shared cache resources. To further enhance intra-group cooperation and cache efficiency, cores are assigned to groups according to consecutive core numbering. For example, cores 0–5 are assigned to Group 1, cores 6–11 to Group 2, and so on, ensuring that cores within the same group are physically proximate.
In this setup, each group has a designated lead core, which is statically assigned as the first core within that group. The lead core fetches input data from main memory or higher-level cache and distributes it to the other cores in the same group. Once each core completes its assigned computation, the results are synchronized within the group to ensure consistency. The lead core then collects the partial results and writes the final data back to global memory.
The complexity of Algorithm 1 is , since only a small number of candidate group configurations are evaluated. In practice, is small, making the overhead negligible. The grouping procedure is summarized in Algorithm 1 and consists of the following steps:
- Enumerate all valid grouping configurations and compute the corresponding cores per group ;
- Evaluate each configuration by estimating its utilization efficiency and applying hardware constraints, including cache capacity and NUMA locality;
- Select the configuration that achieves the highest effective utilization and construct core groups accordingly.
| Algorithm 1 Hardware-Aware Adaptive Core Grouping |
|
4.2. High-Dimensional Partitioning Strategy
Once the core groups are established, the system maps the computational tasks of small and irregular matrices to different core groups. In such matrices, the high-dimensional axis (where the larger dimension is denoted as N) typically exhibits strong independence and weak data dependency, making it well-suited for inter-group parallel partitioning.
The N dimension is evenly divided according to the number of core groups G, with each group responsible for computing a sub-block of the high-dimensional space:
Here, denotes the high-dimensional range assigned to the i-th core group. To control task granularity and avoid oversized sub-blocks, we introduce a threshold parameter a, defined as the maximum size of a high-dimensional block that can be efficiently processed within a group. In practice, a is chosen based on cache capacity and memory bandwidth considerations.
If the size of a sub-block satisfies:
- , the original division is retained;
- , the sub-block is further partitioned into multiple blocks of size a, with the final block possibly smaller.
This threshold-based splitting ensures that each task fits within the effective working set of a core group and improves load balancing across groups.
For example, when totalcore = 32 physical cores are divided into G = 4 core groups with a threshold a = 4096, a high-dimensional space of N = 80,000 is initially partitioned into four sub-blocks, with each group assigned 80,000/4 = 20,000 units. Since 20,000 > a, each group further divides its assigned range into blocks of size a, with the last block containing 3616 units. If the number of core groups is increased to G = 8, each group is assigned 10,000 units, while the same threshold-based partitioning is applied, thereby increasing parallelism and improving load balancing.
4.3. Low-Dimension Partitioning Strategy
After completing the core grouping optimization, the partitioning of the matrix’s smaller dimension, where the smaller dimension is denoted as the M dimension, plays a crucial role in balancing the computational load and improving cache utilization. Unlike the grouping along the larger N dimension, which mainly focuses on inter-group parallelism, the M-dimension partitioning determines how much data each group processes and how effectively cache resources are used. To address this, we propose a group-prior adaptive block partitioning strategy along the M dimension, which balances both workload distribution and cache friendliness.
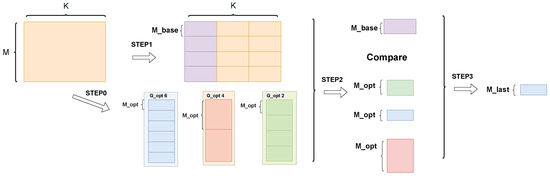
At the beginning of the partitioning process, the system first performs an initial division of the M dimension based on the number of core groups determined in the previous stage:
Let M denote the total size along this dimension. The baseline block size is defined as
This formula produces a concrete set of blocks, where each element represents a feasible partitioning strategy derived from the previous core grouping results. These initial blocks form the foundation for subsequent cache-aware adjustments and adaptive matching between blocks and core groups.
After the grouping phase, the optimal number of groups (e.g., 2, 4, or 6) is determined based on the performance model derived in the previous section. Correspondingly, an initial block size along the M dimension is obtained as:
To further refine cache efficiency and computational balance, is mapped to a predefined candidate set of cache-friendly block sizes:
where each element in corresponds to a tile size that is empirically optimized for cache locality and vectorized computation.
The selection of the final block size follows a deterministic rule:
- If , then ;
- Otherwise, .
This design ensures that the selected block size does not exceed the cache-friendly capacity while maintaining smooth granularity transitions across different matrix sizes.
Through this fine-grained tuning process, the partitioning along the M dimension achieves both cache efficiency and load balance across different core groups and hardware configurations Algorithm 2.
| Algorithm 2 Adaptive High- and Low-Dimensional Partitioning |
|
For example, when and the matrix is divided into four groups, the baseline block size is 96. The system first checks whether this value matches any element in the candidate set (e.g., ). If an exact match is found, it is directly adopted as the final configuration. If not, the system selects the largest candidate smaller than 96 (i.e., the preceding value in the set) as the optimal candidate for subsequent performance testing and fine-tuning. Figure 4.
Figure 4.
Optimal Low-Dimensional Selection.
5. Evaluation
5.1. Experiment Setup
Experimental Platform: Table 2 shows the experimental platform configuration. The following text details the CPU information. To match typical large-model workloads while keeping the input matrices irregular, we use small-scale matrices for our experiments. The dimensions are chosen such that one of the inner GEMM dimensions is moderate, while the other varies over a wide range.
Table 2.
Experimental Platform and Hardware Configuration.
We evaluate the proposed methods on the Kunpeng 920F CPU. The CPU is a system on a chip integrating two computing dies within a single package. Each Die contains four NUMA domains equipped with on-package memory and off-die DDR memory. Each core supports double-precision floating-point SIMD instructions and offers an 8 × 8 matrix computation capability within its pipeline. To enhance data-movement efficiency between DDR and on-package memory, each Die incorporates a System Direct Memory Access (SDMA) interface.
Comparison Method: The Kunpeng CPU includes the BLAS-based Kunpeng Math Library (KML), a high-performance library optimized by Huawei. KML adopts a multi-core parallel strategy in which GEMM tasks are independently scheduled and executed across CPU cores. In our experiments, we compare the proposed AGP method with the native KML GEMM implementation.
To comprehensively evaluate performance, we conduct experiments in three stages. First, we focus on small matrix sizes commonly observed in large model workloads, varying N while keeping the overall problem scale representative, and compare different libraries on both the 920F and 920 5250 platforms. Second, we extend the evaluation on the 920F by exploring more general configurations where M and K are not fixed, in order to assess performance under diverse matrix shapes. Finally, we perform cross-platform comparisons between the 920F and AMD architectures to evaluate the robustness and portability of AGP across different hardware designs.
Experimental criteria: To demonstrate the performance of the proposed method, comparative experiments were conducted on matrices of various shapes and dimensions. We denote the size of a GEMM operation as “”. In the following experiments, we compare the performance of different methods under small and irregular matrix conditions.
In the following comparative experiments, the experimental results are reported in terms of the average GFLOPS (Giga Floating-Point Operations Per Second), calculated as follows:
where M, N and K represent the matrix dimensions, and total_time denotes the execution time on the CPU. Each experiment is executed ten consecutive times, and the reported GFLOPS value represents the arithmetic mean rounded to two decimal places.
5.2. Speed Up with AGP-GEMM
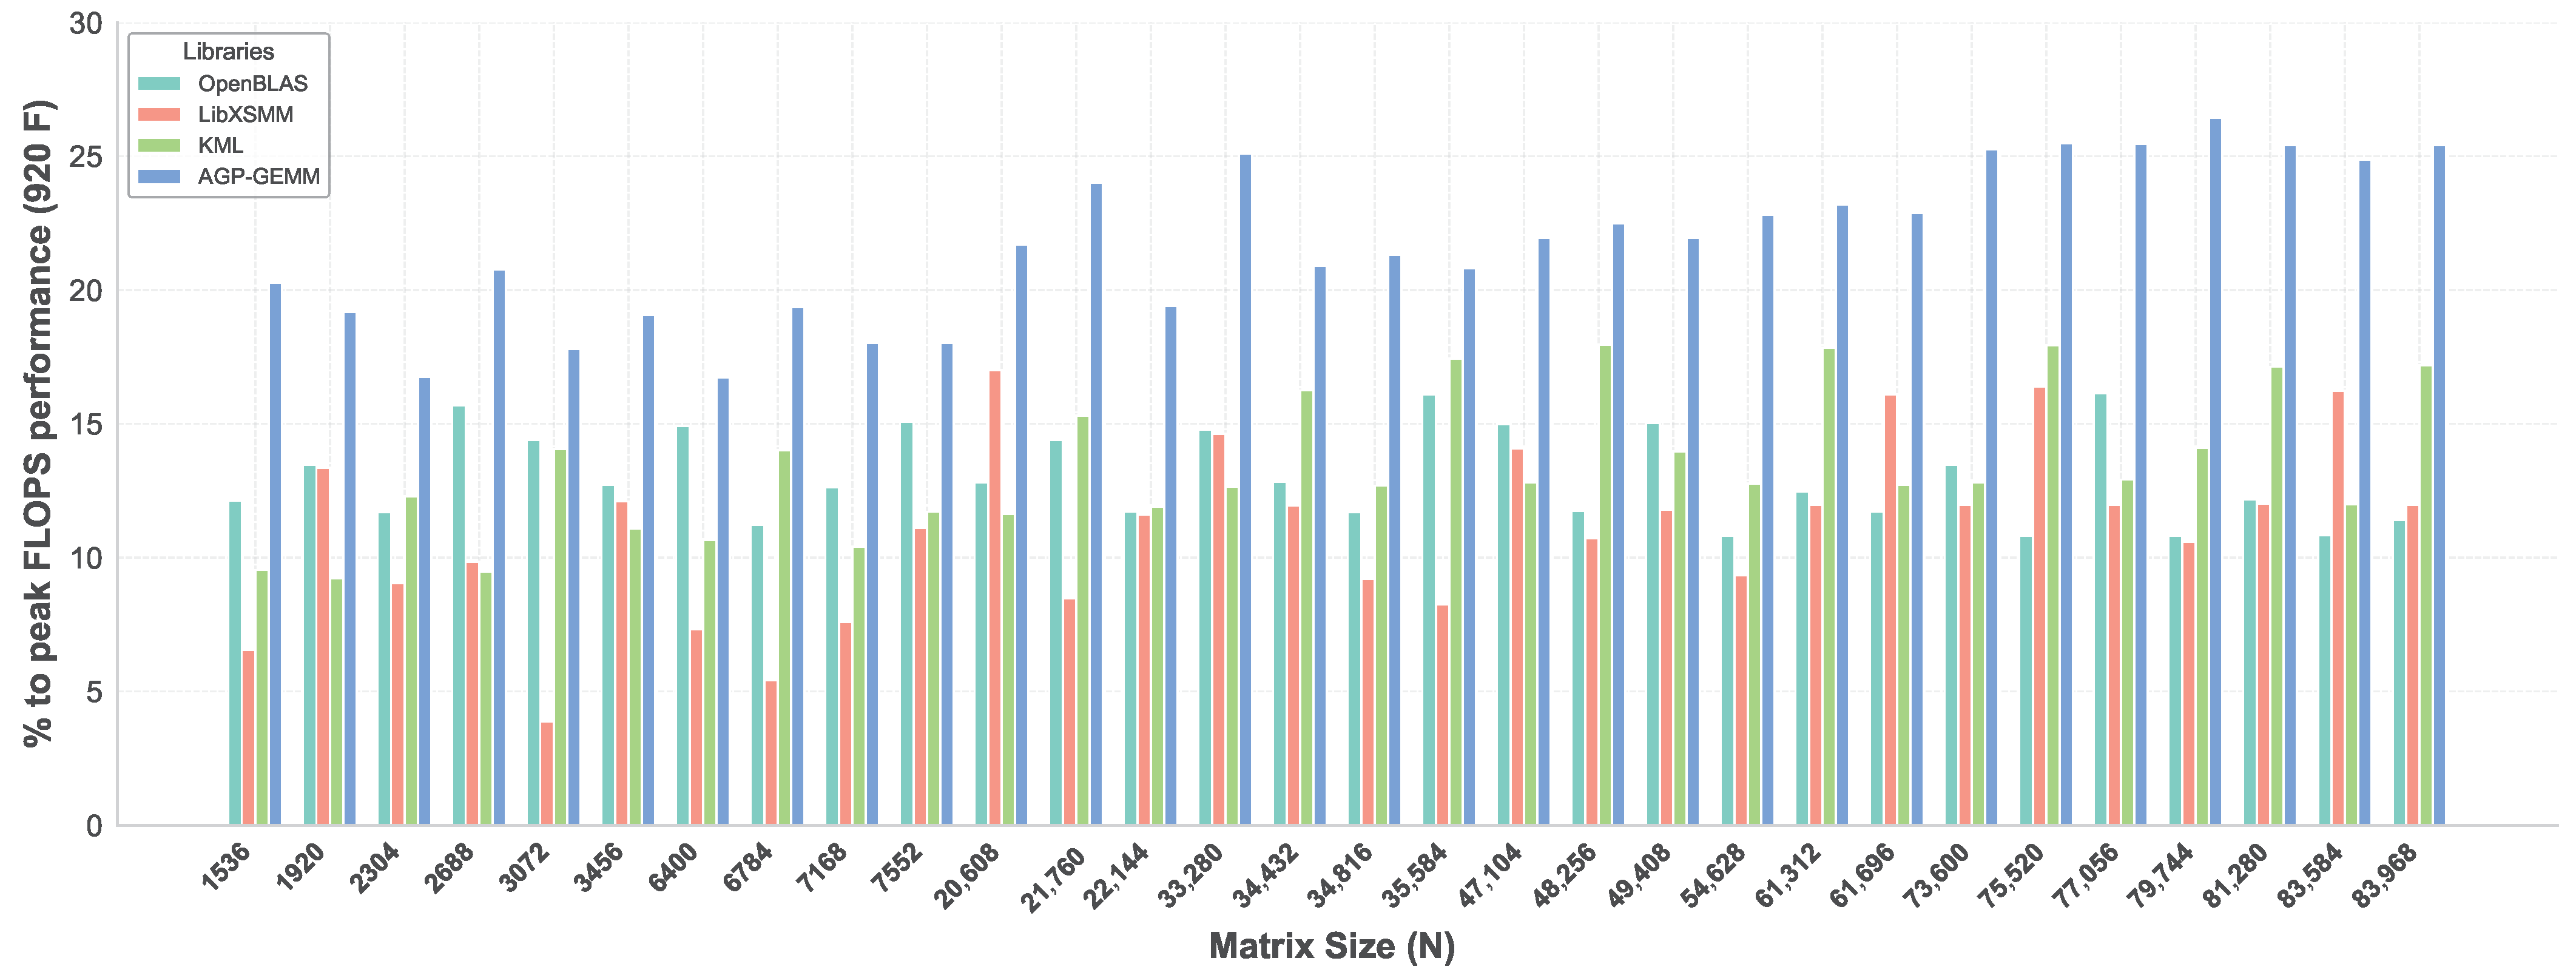
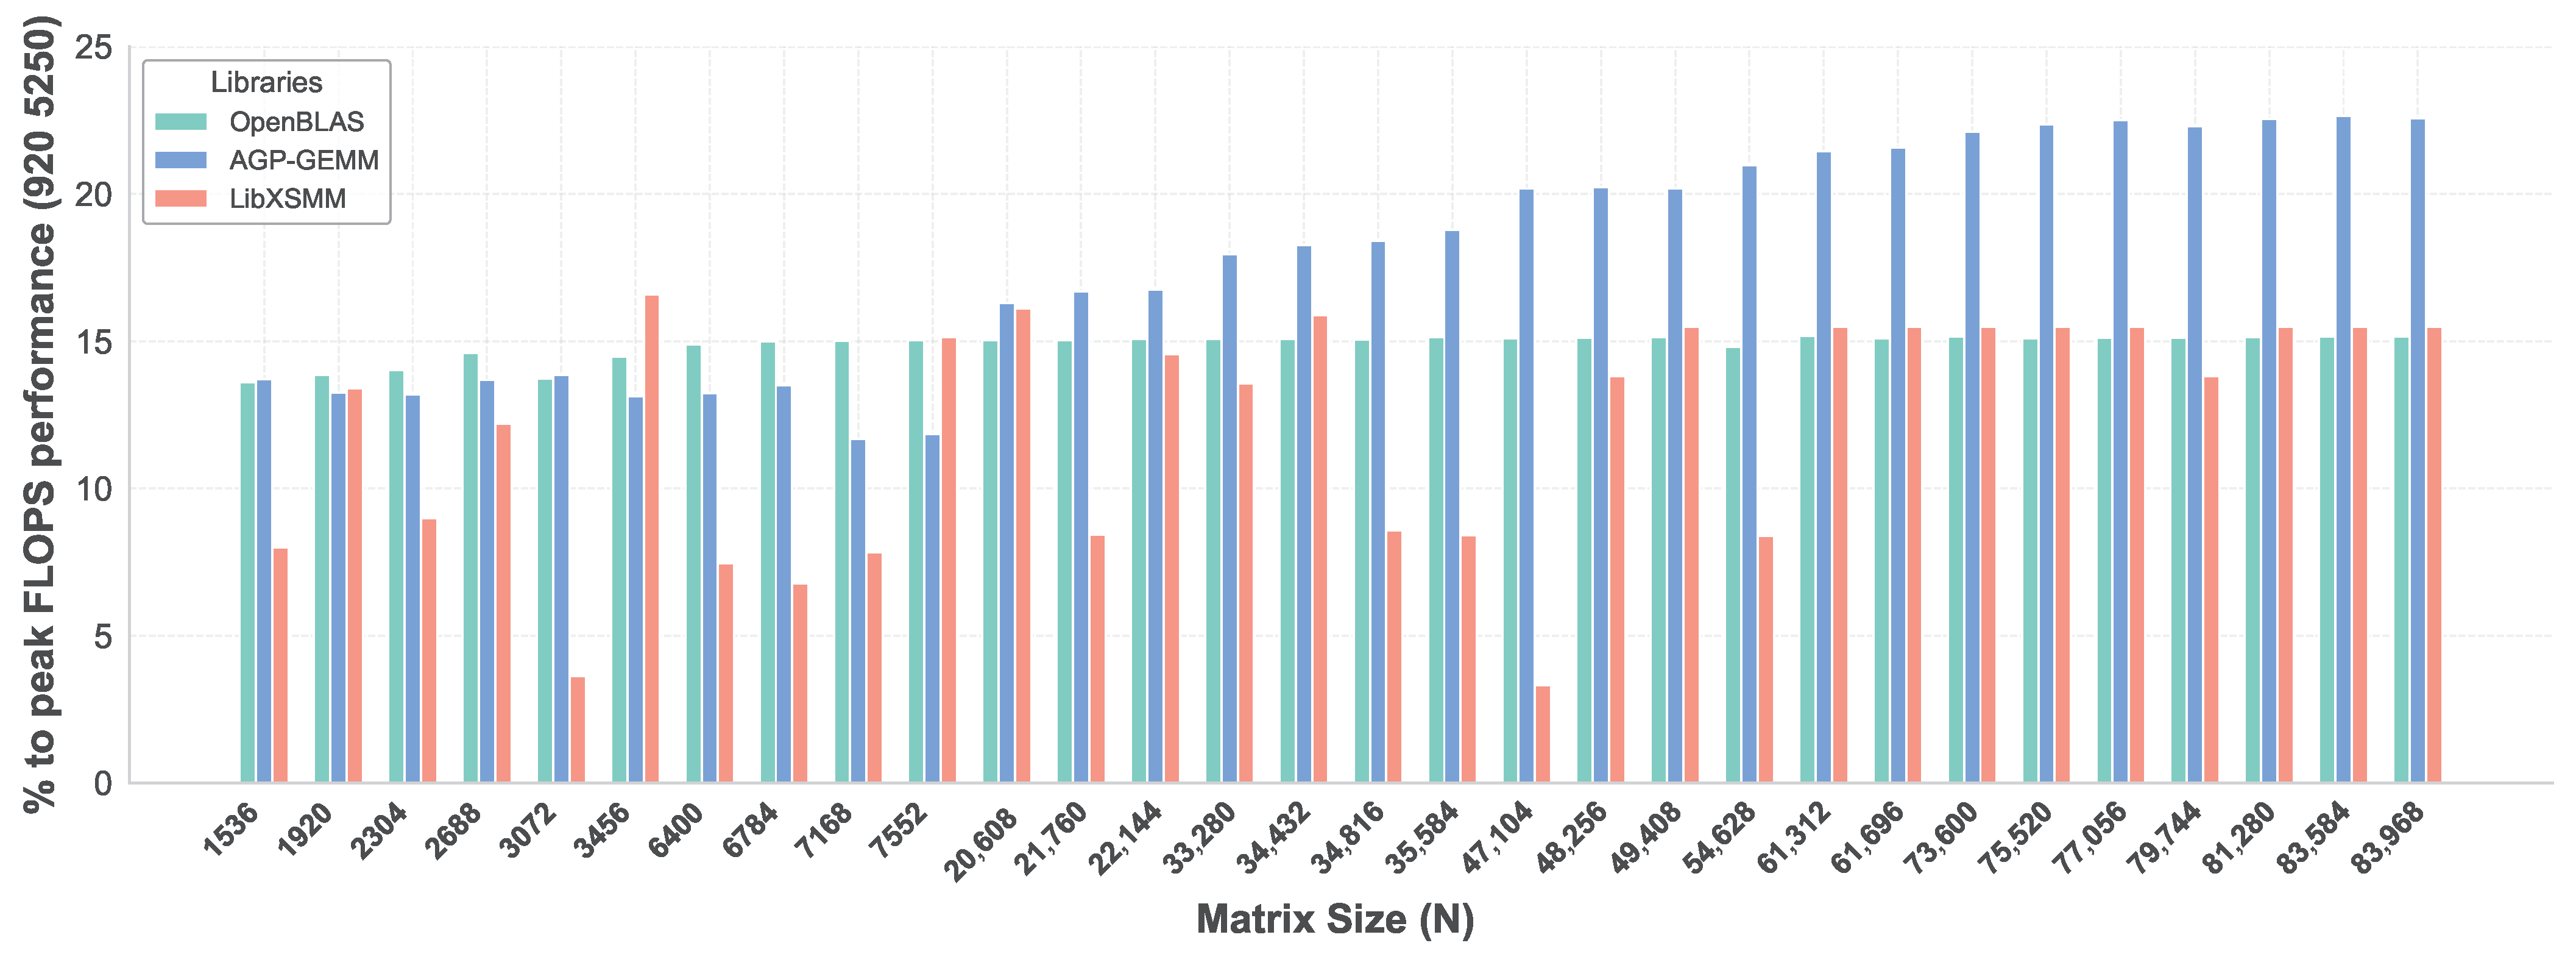
To evaluate the effectiveness of different GEMM libraries for large and irregular matrix sizes, we conduct experiments on the Kunpeng 920F and 920 5250 CPUs. We focus on matrix multiplications with , which corresponds to the hidden dimensions of key layers in large transformer models. In such models, the majority of compute is dominated by matrix multiplications with this hidden dimension. By varying N, we simulate different sequence lengths or batch sizes commonly encountered in practical applications. This experimental setup enables a systematic comparison of baseline libraries (OpenBLAS, LIBXSMM, KML) with AGP-GEMM under realistic workloads, highlighting their performance differences across varying matrix shapes.The detailed experimental results are shown in Figure 5 and Figure 6.
Figure 5.
Performance Comparison of GEMM Libraries on Kunpeng 920F Across Varying N.
Figure 6.
Performance Comparison of GEMM Libraries on Kunpeng 5250 Across Varying N.
Figure 5 shows the relative performance of all libraries on the 920F as N increases. AGP-GEMM consistently achieves the highest performance, providing up to 2.1× speedup over the best-performing baseline. Across the tested matrices, AGP-GEMM achieves 1.5–2.5× speedup over OpenBLAS and 1.6–2.1× over KML, and 2.2–3.5× over LIBXSMM, reflecting its improved core utilization and memory scheduling.
Figure 6 shows the relative performance of all libraries on the 920 5250 as N increases. AGP-GEMM consistently achieves the highest performance, providing up to 1.7× speedup over the best-performing baseline. Across the tested matrices, AGP-GEMM achieves 1.5–2.5× speedup over OpenBLAS and 1.2–2.1× over LIBXSMM, demonstrating its more efficient core utilization and memory scheduling.
To better understand this trend, we observe that as N increases, the available parallelism across core groups becomes fully exploited. Once all groups are actively engaged, further increases in N only enlarge the workload per group rather than increasing parallelism. As a result, performance gradually approaches a saturation point. In this regime, execution becomes bounded by hardware constraints such as peak compute throughput and memory bandwidth, rather than the efficiency of individual libraries. This behavior is consistently observed across both the 920F and 920 5250 platforms.
5.3. Performance Comparison on 920F and AMD Platforms
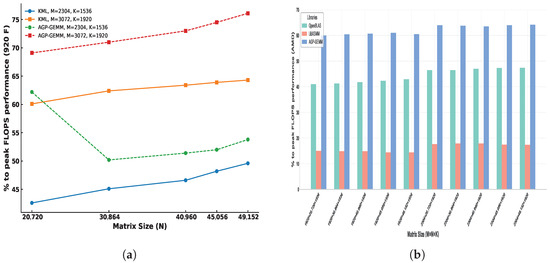
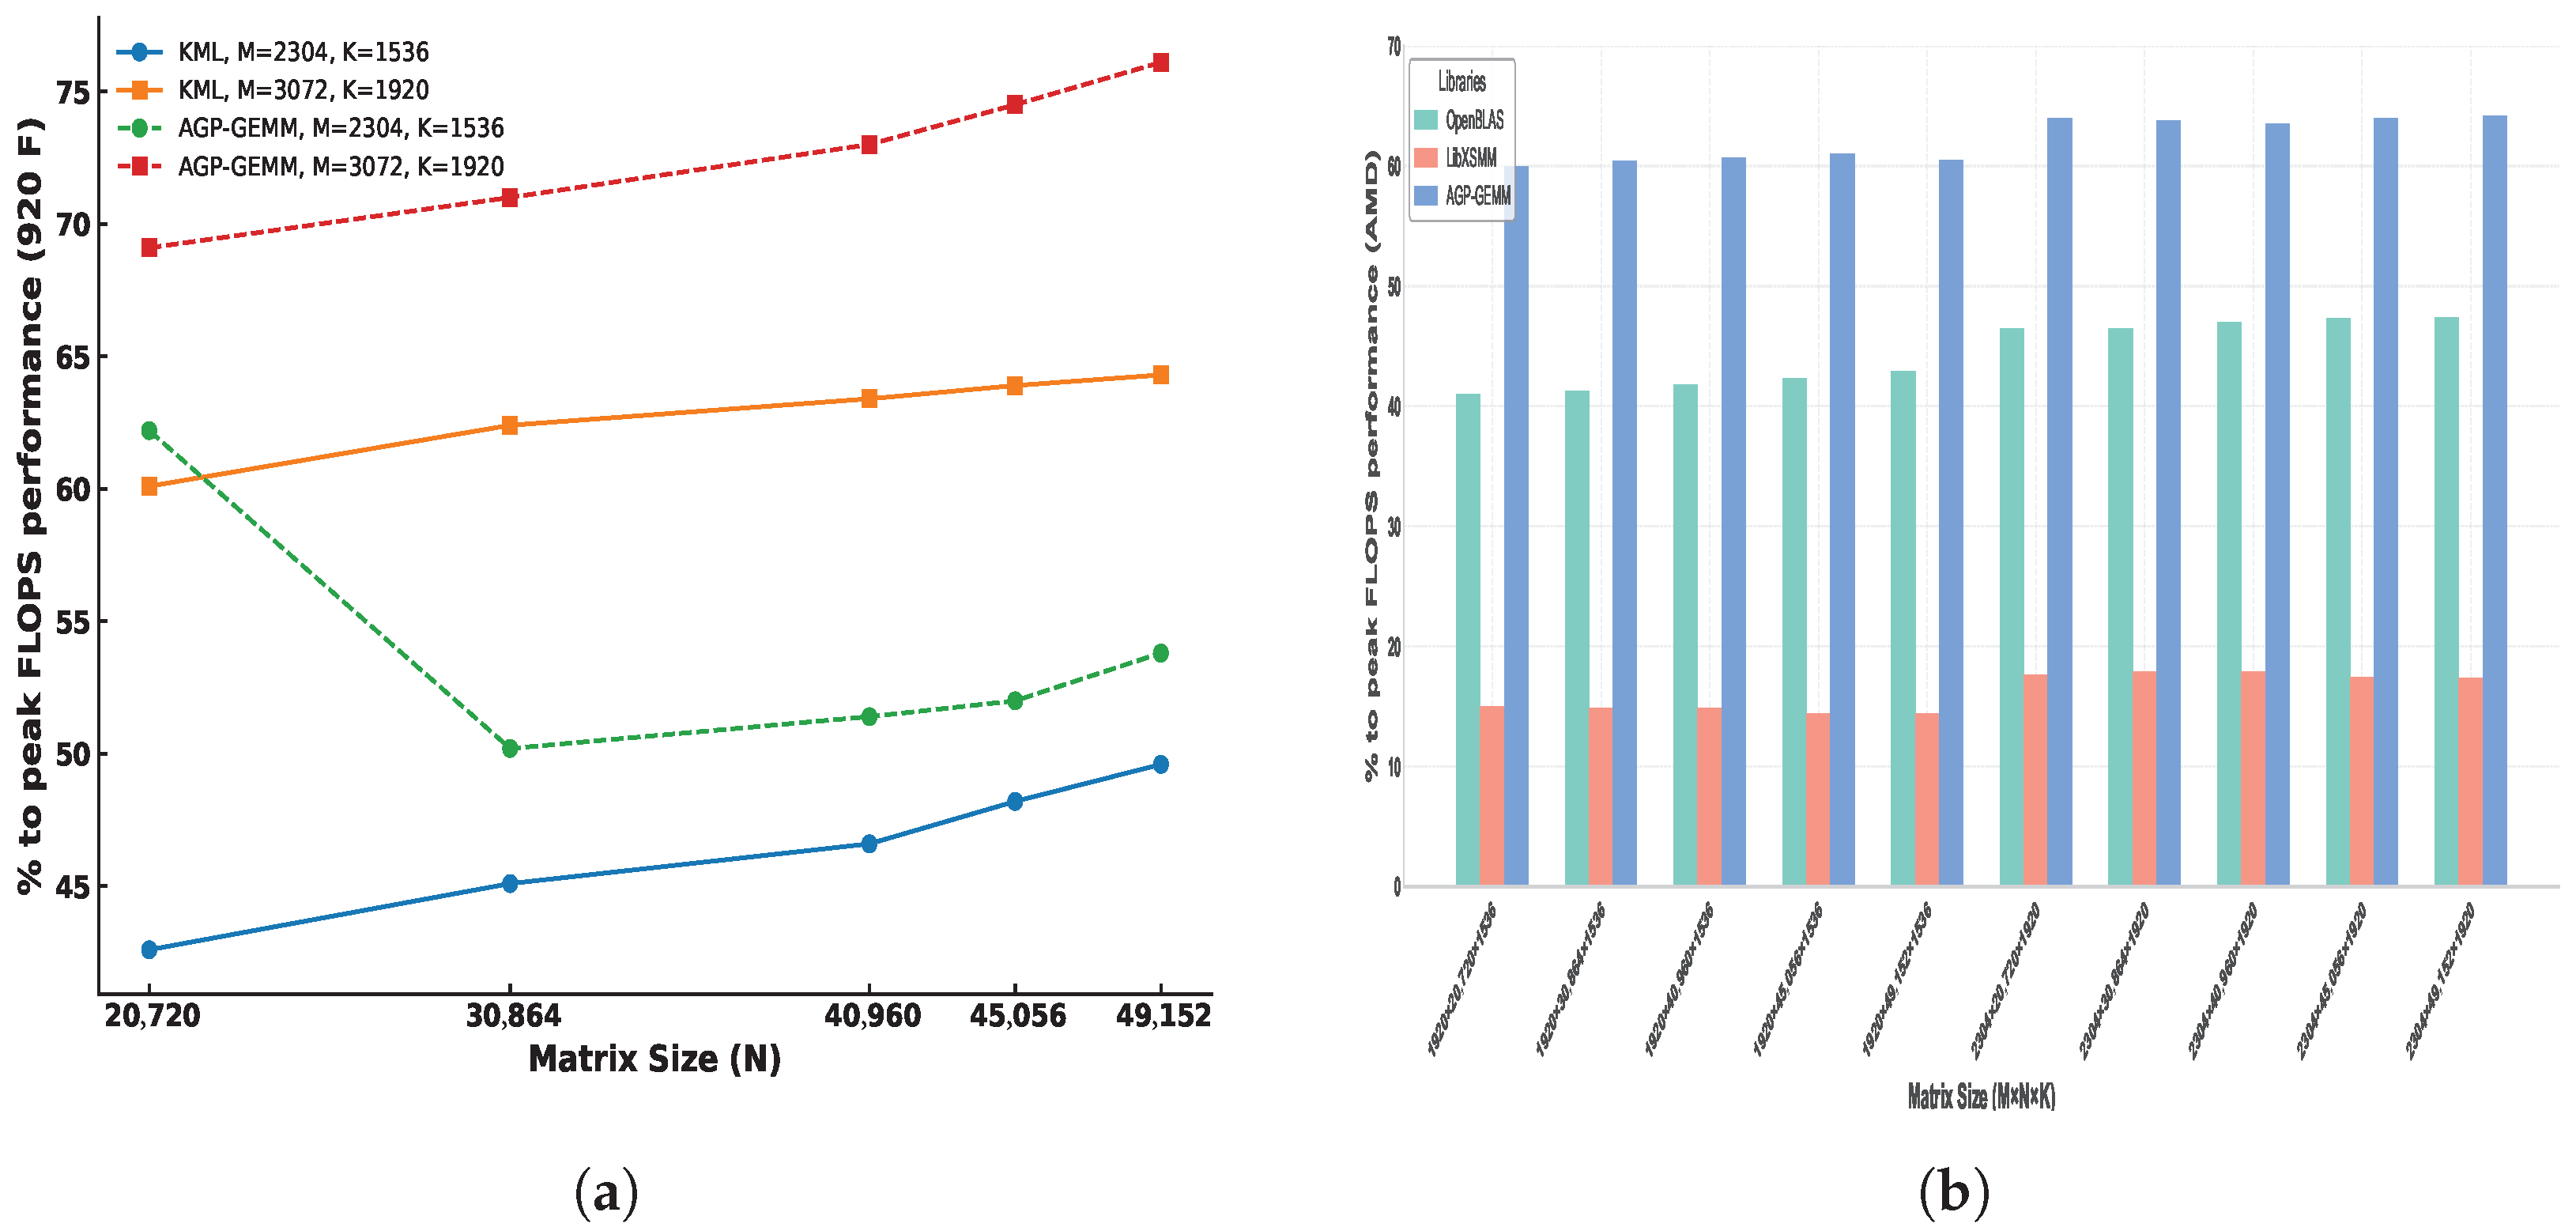
Figure 7a shows the relative performance of KML and AGP-GEMM on the 920F as N increases. AGP-GEMM consistently achieves the highest performance, providing up to 2.3× speedup over the best-performing baseline. Across the tested matrices, AGP-GEMM achieves 1.5–2.5× speedup over OpenBLAS and 1.6–2.1× over KML, while consistently outperforming LIBXSMM. For instance, at moderate matrix sizes (e.g., , , ), AGP-GEMM achieves around 2.0× speedup over OpenBLAS and 1.8× over KML. On larger matrices, such as , , , AGP-GEMM maintains 1.5–1.8× speedup over OpenBLAS and 1.6–1.9× over KML, demonstrating its consistent advantage and efficient core utilization and memory scheduling across all sizes.
Figure 7.
Relative performance of different platforms (a,b). (a) Relative performance of KML and AGP-GEMM on the 920F across different matrix sizes. (b) Relative performance of different platforms on the AMD across different matrix sizes.
Figure 7b presents the relative performance of OpenBLAS, Libxsmm, and AGP-GEMM on the AMD platform as N increases. AGP-GEMM consistently achieves the highest performance, providing up to 1.7× speedup over the best-performing baseline. Across the tested matrices, AGP-GEMM achieves 1.5–2.5× speedup over OpenBLAS and 1.2–2.1× over Libxsmm. For example, at smaller matrix sizes (, , ), AGP-GEMM shows approximately 2.0× speedup over OpenBLAS, while at larger sizes (, , ) it maintains 1.7–1.8× speedup. These results highlight AGP-GEMM’s consistent performance advantage and efficient utilization of computational resources compared to the baseline libraries.
5.4. The Ablation Experiment Result Analysis with AGP-GEMM
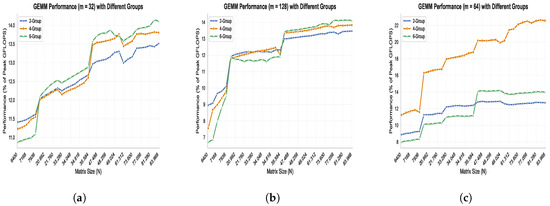
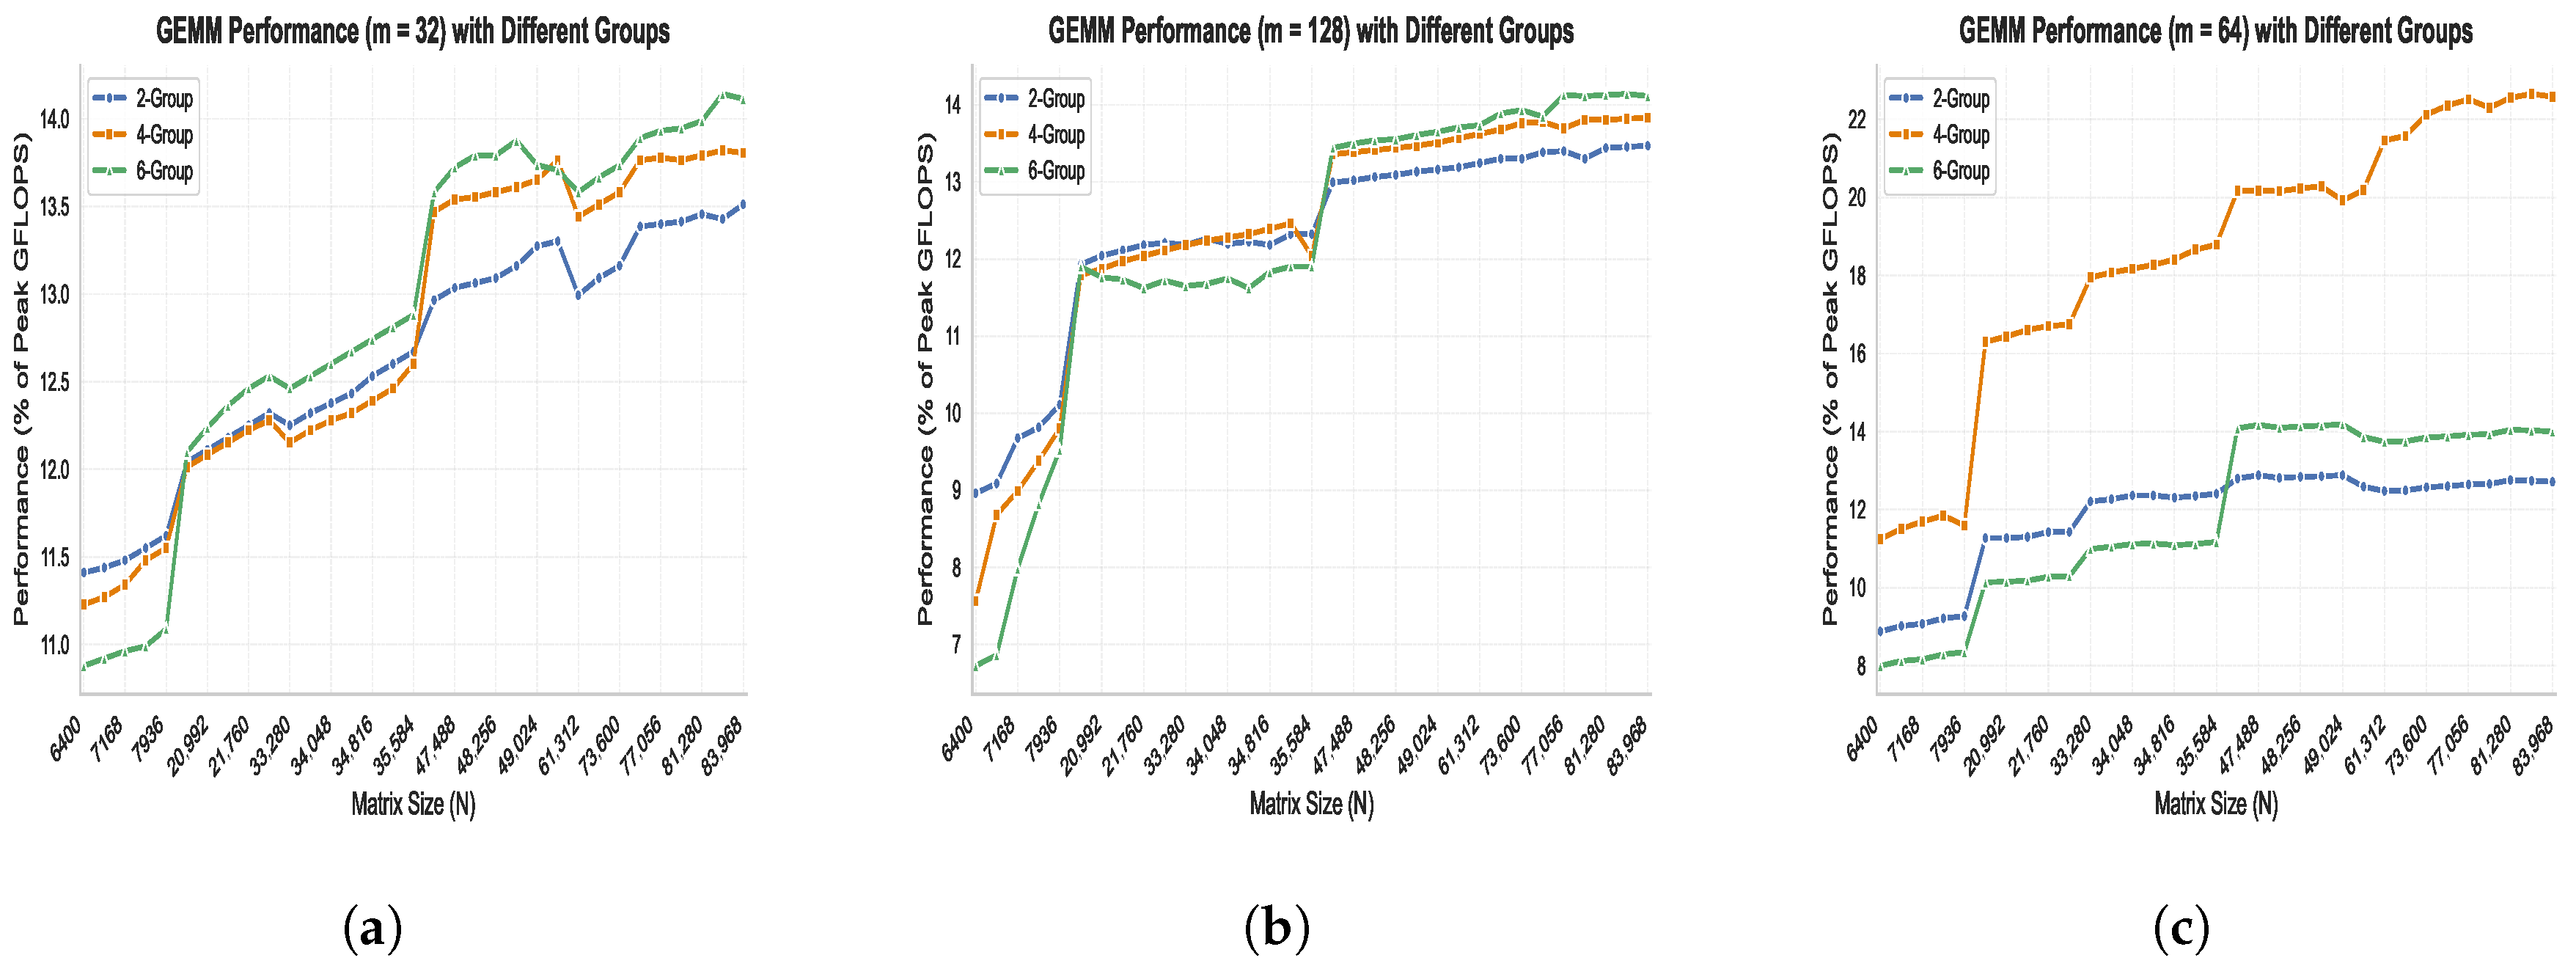
To provide a more thorough evaluation of the proposed method, we conduct an ablation study based on the techniques introduced in Section 4, quantifying the individual performance contributions of each component. The detailed comparative results are presented in Figure 8a–c.
Figure 8.
Core group configurations under different matrix sizes on Kunpeng 920F. Subpanels can be referenced individually as (a–c). (a) Core group configurations with . (b) Core group configurations with . (c) Core group configurations with .
When , the performance of all grouping schemes increases steadily with N. In the small-N region, all schemes achieve around 10–11.5% of peak performance. As N grows, the curves gradually separate, with the six-group scheme reaching about 14–14.5%, the four-group scheme around 13–14%, and the two-group scheme about 13%. The corresponding global peak speedups are approximately 1.77×, 1.72×, and 1.64× for the six-, four-, and two-group schemes, respectively (Figure 8a).
When , the performance becomes smoother and slightly higher overall. All schemes start from around 11–12% and gradually converge to 13–14% as N increases. The performance differences among grouping strategies are relatively small, with all configurations achieving similar peak speedups of around 1.6× (Figure 8b).
When , the performance differences among grouping schemes become the most pronounced. In the small-N region, all schemes operate at relatively low efficiency (8–11%). As N increases, the four-group scheme improves significantly, reaching up to 18–19% of peak performance, while the six- and two-group schemes remain around 14% and 12%, respectively. Overall, the four-group configuration achieves the best performance, with an average speedup of approximately 1.64× and a peak speedup of up to 2.10× (Figure 8c).
The observed performance differences across different M values mainly stem from the trade-off between task granularity and hardware resource utilization. Since the matrices considered are relatively small, overly fine partitioning along the M dimension allows more cores to be engaged but increases overhead and reduces per-core efficiency. Conversely, overly coarse partitioning underutilizes available cores, leading to lower performance. The case of represents a balanced regime where task size and core assignment achieve an effective compromise, maximizing parallelism while maintaining high resource utilization. Notably, this value of is determined by our adaptive low-dimensional partitioning algorithm, which selects a cache-friendly block size based on the number of core groups and candidate block sizes, rather than being chosen arbitrarily. As a result, produces the largest performance differences among grouping strategies.
5.5. Total Time with AGP-GEMM
5.5.1. Pipeline Time with AGP-GEMM
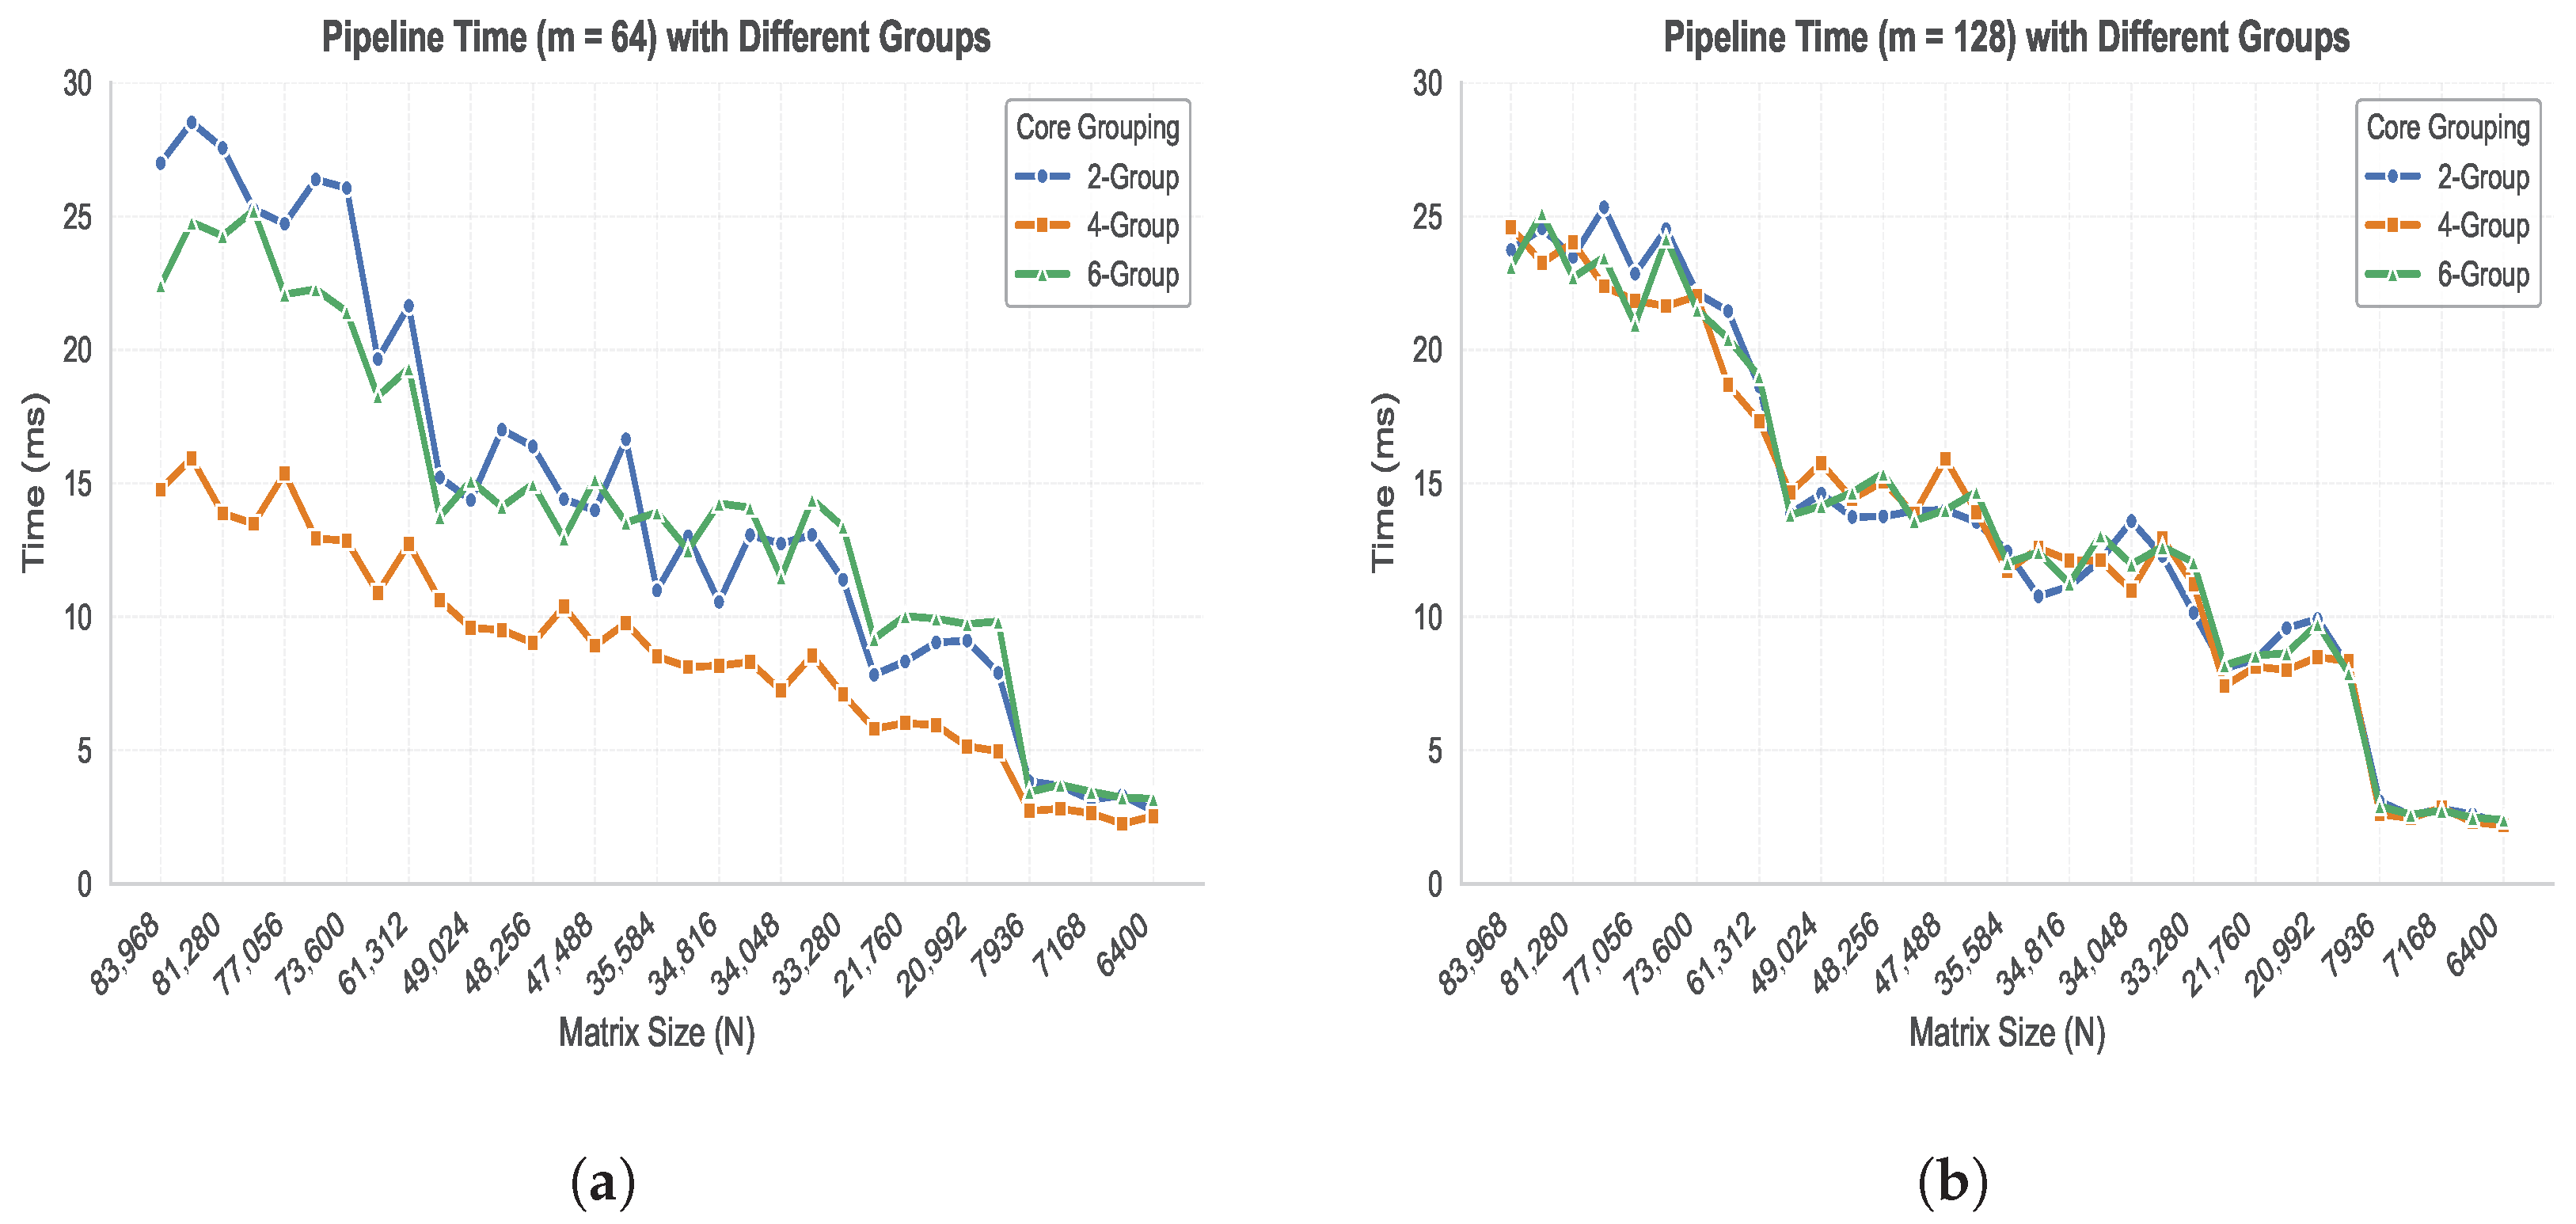
For , the pipeline execution times under different core grouping schemes are shown in Figure 9a. Overall, the pipeline time increases with the matrix width N, while both the growth rate and stability differ significantly across groupings. The two-core grouping exhibits pipeline times of approximately 2.7 ms to 3.8 ms for small matrices (N < 10,000), which increase to 8 ms to 17 ms for medium-sized matrices (20,000 ≤ N ≤ 50,000), and further rise to 25 ms to 29 ms for large matrices (N > 80,000). This behavior indicates limited pipeline depth and low parallel utilization.
Figure 9.
Pipeline execution time under different M configurations. Subpanels can be referenced individually as (a,b). (a) Pipeline execution time for . (b) Pipeline execution time for .
In contrast, the four-core grouping demonstrates the most stable performance across all matrix sizes, achieving 2.5 ms to 2.8 ms for small N, 5 ms to 10 ms for medium N, and 13 ms to 16 ms for large N. This stability reflects effective overlap between computation and memory access. The six-core grouping slightly outperforms the two-core scheme in certain cases; however, it exhibits significant fluctuations as N increases (12 ms to 25 ms), mainly due to increased thread synchronization overhead and cache contention. Overall, the four-core grouping achieves the best balance among parallel depth, cache sharing, and thread coordination, thereby maximizing pipeline utilization and overall throughput.
For , the pipeline execution times under different core grouping schemes are illustrated in Figure 9b. Similar to the case, the pipeline time generally increases with the matrix width N, while the performance differences among grouping schemes become more pronounced. The two-core grouping performs relatively fast and stable for small matrices, with execution times of approximately 2.2 ms to 3 ms. However, as N increases, the execution time grows rapidly, reaching 8 ms to 13 ms for medium-sized matrices and exceeding 20 ms for large matrices, indicating limited scalability.
The four-core grouping again exhibits the most stable behavior, achieving 2.1 ms to 2.8 ms for small matrices, 7 ms to 15 ms for medium-sized matrices, and 17 ms to 24 ms for large matrices, with only minor fluctuations. This trend demonstrates good overlap between computation and memory access. Although the six-core grouping attains the lowest execution times in some medium-sized cases (2.4 ms to 2.6 ms), its performance varies more significantly as N increases, and the execution time can exceed 20 ms for large matrices due to synchronization overhead and cache contention. Consequently, the four-core grouping provides the best compromise among parallel depth, cache sharing, and pipeline scheduling, making it the most effective and scalable configuration.
5.5.2. Synchronization Time Analysis with AGP-GEMM
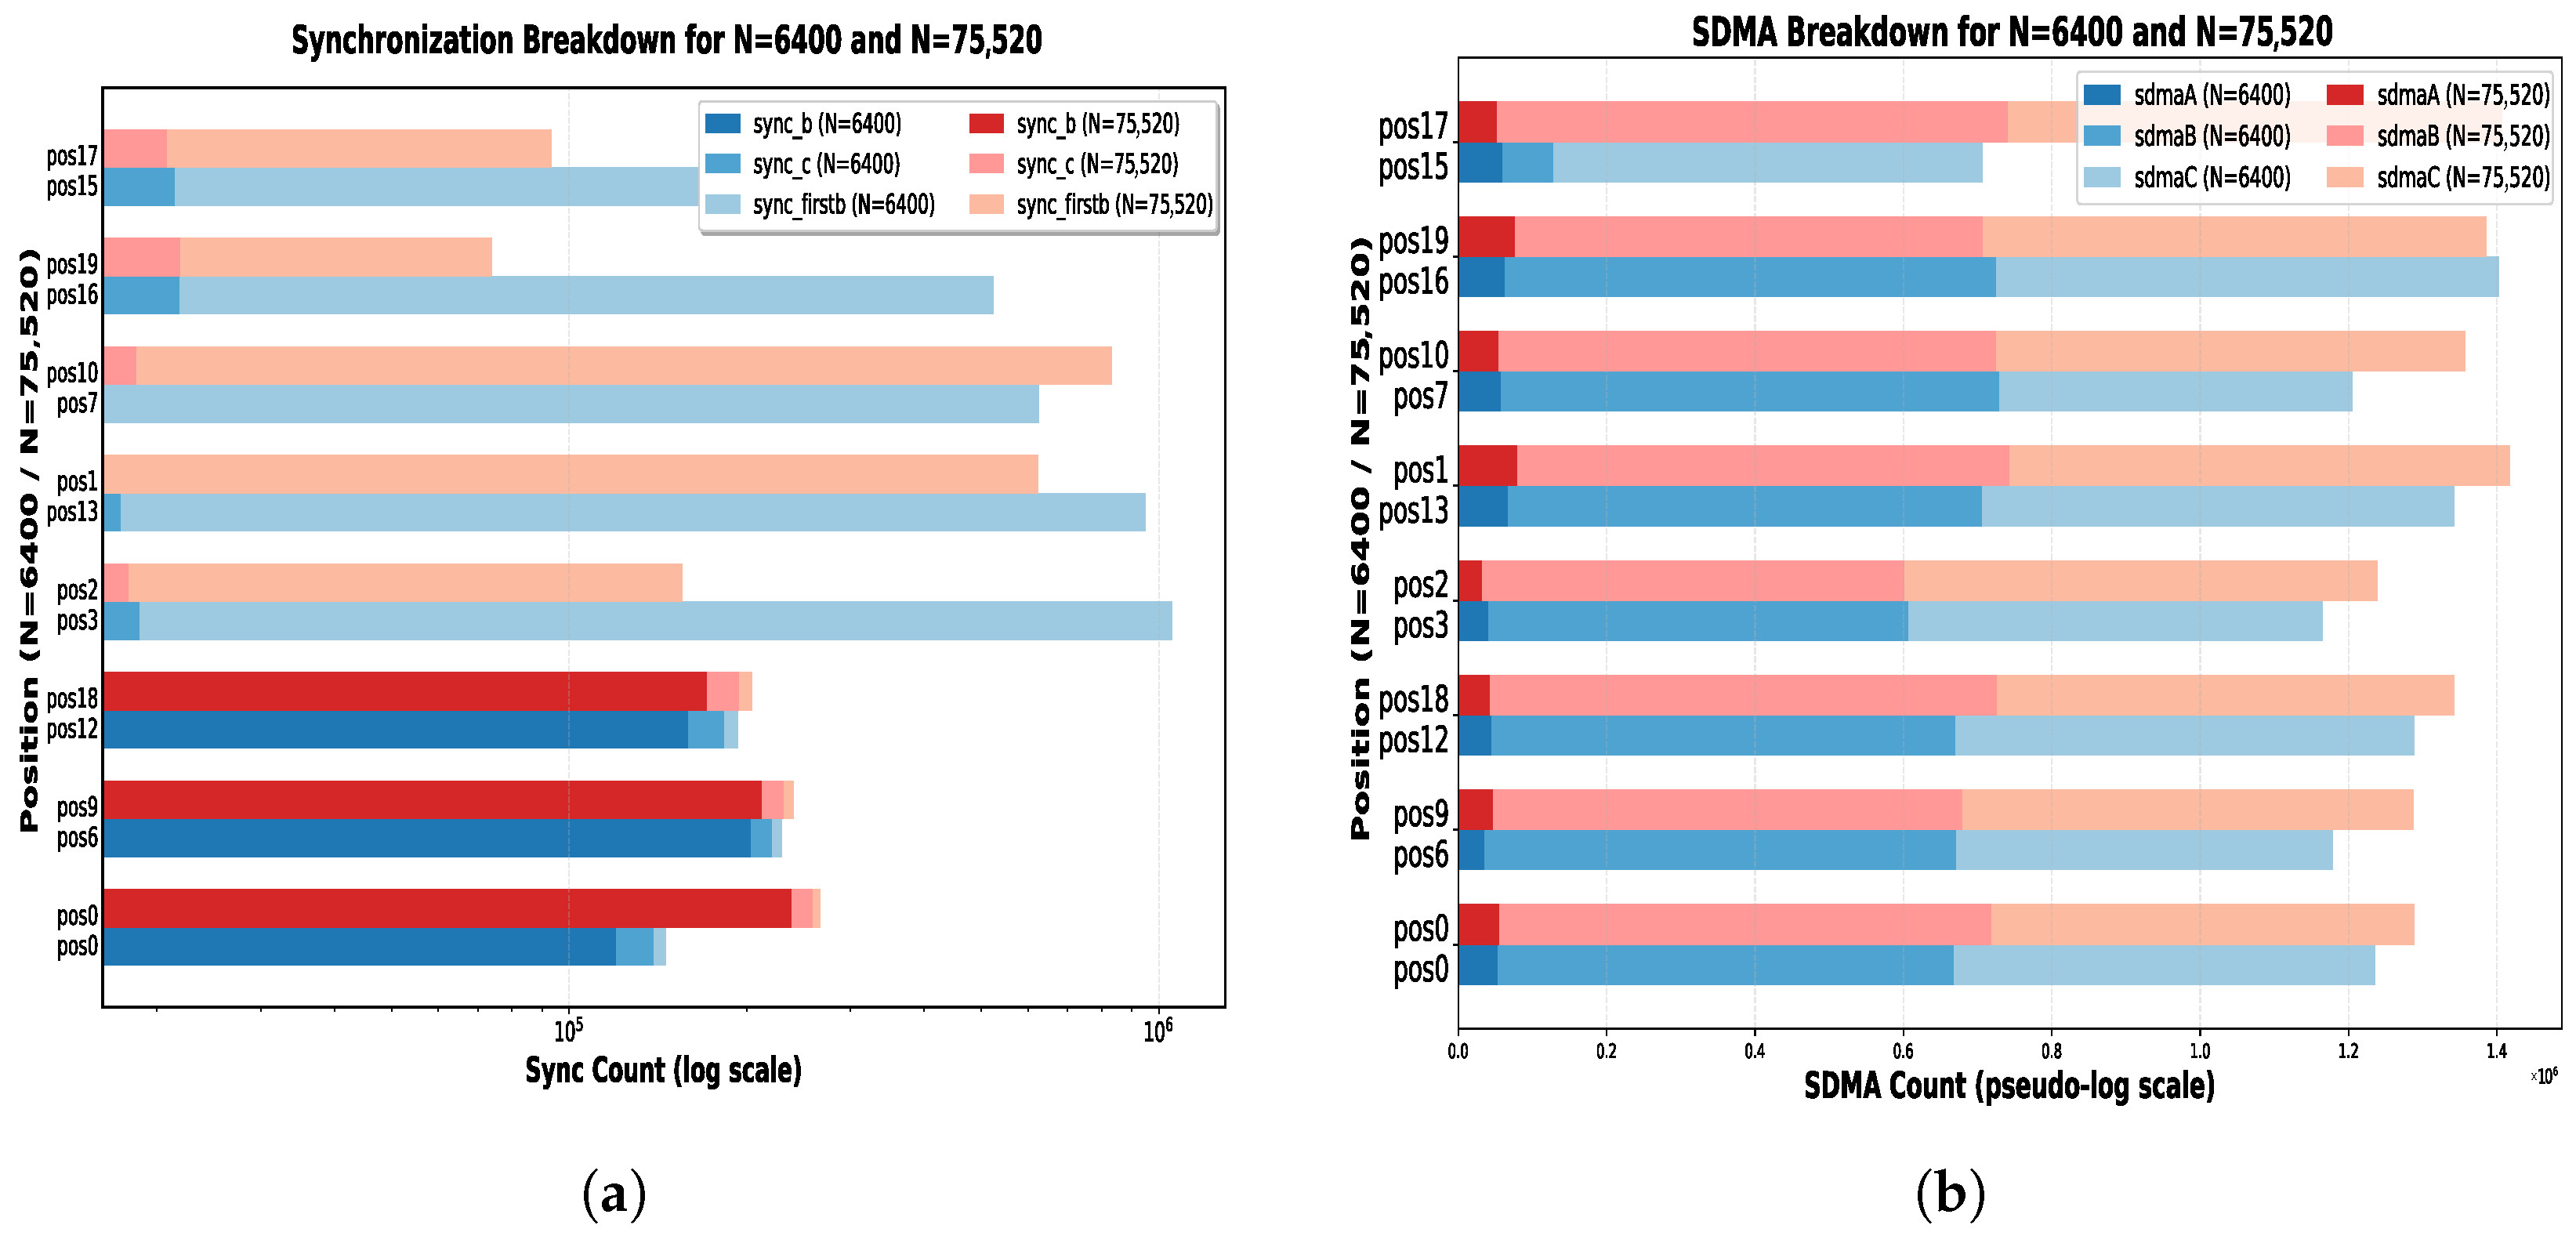
Figure 10 presents the synchronization and SDMA data transfer overheads across different thread positions for matrix sizes and . As shown in Figure 10a, the synchronization overhead varies significantly across thread positions under both configurations. For synchronization associated with the high-dimensional matrix along the N dimension, the sync_b overhead is mainly concentrated at master thread positions (e.g., pos 0, 9, and 18 for , and pos 0, 6, and 12 for ), remaining on the order of cycles and exhibiting an increasing trend as N grows.
Figure 10.
Pipeline execution time under different M configurations. Subpanels can be referenced individually as (a,b). (a) Pipeline execution time for . (b) The breakdown of SDMA transmission time .
In contrast, the first synchronization of the high-dimensional matrix, denoted as sync_first, shows pronounced peaks at non-master thread positions, with overheads typically reaching the order of cycles and dominating the overall synchronization cost. This phenomenon primarily occurs during the group initialization phase, reflecting the latency incurred while threads wait for matrix data to become fully available before computation begins. Although subsequent synchronization events occur more frequently, their per-event cost is significantly lower, resulting in a reduced amortized overhead.
As illustrated in Figure 10b, the SDMA overhead also varies across thread positions for and . The SDMA cost associated with matrix A remains relatively low and stable due to its smaller data volume and limited pressure on memory bandwidth. In contrast, the SDMA overhead for the high-dimensional matrix along the N dimension is substantially higher and increases noticeably with N. Master threads incur relatively high SDMA costs because they are responsible for initiating and coordinating data transfers, while certain non-master threads experience even higher peaks when waiting for SDMA operations involving large data blocks to complete.
Although the grouped computation model introduces additional synchronization overhead—particularly at master thread positions responsible for coordinating data transfers—this cost is effectively offset by the significant improvement in computing core utilization, leading to an overall performance gain. Furthermore, SDMA data transfers can be overlapped with computation in a pipelined manner: while the SDMA hardware transfers the next block of high-dimensional matrix data, the computing threads simultaneously process the current block, thereby substantially reducing core idle time and improving overall execution efficiency.
6. Conclusions and Future Work
To address the issues of load imbalance and low hardware utilization in small and irregular matrix multiplication scenarios, this paper proposes a load-balanced GEMM acceleration method, AGP-GEMM. The approach employs a multi-threaded kernel to balance computational and data workloads, and introduces a dynamic core grouping strategy that partitions physical cores into cooperative groups sharing cache resources and task queues. The optimal grouping configuration is dynamically selected based on matrix size and task granularity. High-dimensional matrices are partitioned across groups to achieve inter-group parallelism, while low-dimensional matrices adopt an adaptive block partitioning strategy to improve cache utilization and load balance. Experiments on the Kunpeng platform demonstrate that AGP-GEMM achieves approximately 2.1× speedup over traditional CPU BLAS implementations (e.g., OpenBLAS, MKL), which is comparable to the performance improvements observed with GPU acceleration in scientific computing. In particular, CPU-only GEMM optimization remains highly relevant in scenarios where GPU resources are limited or host-side preprocessing is required.
This method provides a general and efficient framework for CPU-side small-matrix GEMM parallelization and lays the groundwork for future extensions. With the rapid development of large language models, GEMM operations are increasingly critical in both training and inference. However, modern models often rely on lower-precision formats such as FP16 and FP8, presenting new challenges for performance and storage efficiency. Therefore, future work may explore mixed-precision computation, adaptive data layout strategies, and support for diverse processor architectures and memory access patterns, further enhancing GEMM efficiency and scalability across different precision levels and hardware platforms.
Author Contributions
H.Z.: Writing—review & editing, Writing—original draft. L.L.: Writing—review & editing, Supervision. H.Y.: Supervision, Conceptualization. Y.Z.: Supervision, Conceptualization. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by the Natural Science Foundation of Guangdong Province, China, grant number 2024A1515010204. Huawei Technologies Co., Ltd. provided access to the Kunpeng 920F platform and technical support.
Data Availability Statement
No data was used for the research described in the article.
Conflicts of Interest
The authors declare that they have no known competing financial interests or personal relationships that could have appeared to influence the work reported in this paper.
References
- Venkatesh, S.; Muralikrishnan, S.; Narayanan, P.J. (Eds.) High Performance Computing; Lecture Notes in Computer Science; Springer: Cham, Switzerland, 2016; Volume 10037. [Google Scholar] [CrossRef] [Scilit]
- Davies, T.; Karlsson, C.; Liu, H.; Ding, C.; Chen, Z. High Performance Linpack Benchmark: A Fault-Tolerant Implementation without Checkpointing. In Proceedings of the International Conference on Supercomputing (ICS ’11); ACM: New York, NY, USA, 2011; pp. 162–171. [Google Scholar] [CrossRef] [Scilit]
- Li, Y.; Miao, R.; Liu, H.H.; Zhuang, Y.; Feng, F.; Tang, L.; Cao, Z.; Zhang, M.; Kelly, F.; Alizadeh, M.; et al. HPCC: High Precision Congestion Control. In Proceedings of the ACM Special Interest Group on Data Communication (SIGCOMM ’19); ACM: New York, NY, USA, 2019; pp. 44–58. [Google Scholar] [CrossRef] [Scilit]
- Hwang, R.; Kang, M.; Lee, J.; Kam, D.; Lee, Y.; Rhu, M. GROW: A Row-Stationary Sparse–Dense GEMM Accelerator for Memory-Efficient Graph Convolutional Neural Networks. In Proceedings of the IEEE International Symposium on High-Performance Computer Architecture (HPCA); IEEE: New York, NY, USA, 2023; pp. 42–55. [Google Scholar] [CrossRef] [Scilit]
- Silva, I.D.A.; Carle, T.; Gauffriau, A.; Jegu, V.; Pagetti, C. A Predictable SIMD Library for GEMM Routines. In Proceedings of the IEEE Real-Time and Embedded Technology and Applications Symposium (RTAS); IEEE: New York, NY, USA, 2024; pp. 55–67. [Google Scholar] [CrossRef] [Scilit]
- Meyer, M. Towards Performance Characterization of FPGAs in Context of HPC Using OpenCL Benchmarks. In Proceedings of the International Symposium on Highly Efficient Accelerators and Reconfigurable Technologies (HEART), Online, 21–23 June 2021. [Google Scholar]
- Patankar, S.V.; Spalding, D.B. A Calculation Procedure for Heat, Mass and Momentum Transfer in Three-Dimensional Parabolic Flows. In Numerical Prediction of Flow, Heat Transfer, Turbulence and Combustion; Patankar, S.V., Pollard, A., Singhal, A.K., Vanka, S.P., Eds.; Pergamon: Oxford, UK, 1983; pp. 54–73. [Google Scholar] [CrossRef] [Scilit]
- Feng, J.; Qi, Y.; Xu, R.; Pandey, S.; Chu, X. Turbulence.ai: An end-to-end AI scientist for fluid mechanics. Theor. Appl. Mech. Lett. 2026, 16, 100620. [Google Scholar] [CrossRef] [Scilit]
- Aldossary, A.; Campos-Gonzalez-Angulo, J.A.; Pablo-García, S.; Leong, S.X.; Rajaonson, E.M.; Thiede, L.; Tom, G.; Wang, A.; Avagliano, D.; Aspuru-Guzik, A. In Silico Chemical Experiments in the Age of AI: From Quantum Chemistry to Machine Learning and Back. Adv. Mater. 2024, 36, 2402369. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Antolini, A.; Zavalloni, F.; Lico, A.; Vignali, R.; Iannelli, L.; Zurla, R.; Bertolini, J.; Calvetti, E.; Pasotti, M.; Scarselli, E.F.; et al. Controlled Acceleration of PCM Cells Time Drift Through On-Chip Current-Induced Annealing for AIMC Multilevel MVM Computation. IEEE Trans. Electron. Devices 2025, 72, 215–221. [Google Scholar] [CrossRef] [Scilit]
- Mackin, C.; Narayanan, P.; Ambrogio, S.; Tsai, H.; Spoon, K.; Fasoli, A.; Chen, A.; Friz, A.; Shelby, R.M.; Burr, G.W. Neuromorphic Computing with Phase Change: Device Reliability and Variability Challenges. In 2020 IEEE International Reliability Physics Symposium (IRPS); IEEE: New York, NY, USA, 2020; pp. 1–10. [Google Scholar] [CrossRef] [Scilit]
- Spoon, K.; Ambrogio, S.; Narayanan, P.; Tsai, H.; Mackin, C.; Chen, A.; Fasoli, A.; Friz, A.; Burr, G.W. Accelerating Deep Neural Networks with Analog Memory Devices. In IEEE International Memory Workshop (IMW); IEEE: New York, NY, USA, 2020; pp. 1–4. [Google Scholar] [CrossRef] [Scilit]
- OpenBLAS: An Optimized BLAS Library. Available online: http://www.openblas.net/ (accessed on 20 March 2026).
- Van Zee, F.G.; Van De Geijn, R.A. BLIS: A Framework for Rapidly Instantiating BLAS Functionality. ACM Trans. Math. Softw. 2015, 41, 1–33. [Google Scholar] [CrossRef] [Scilit]
- Arm Ltd. Arm Performance Libraries Reference Manual. Arm Developer Documentation. 2025. Available online: https://developer.arm.com (accessed on 20 March 2026).
- Masliah, I.; Abdelfattah, A.; Haidar, A.; Tomov, S.; Baboulin, M.; Falcou, J.; Dongarra, J. Algorithms and Optimization Techniques for High-Performance Matrix–Matrix Multiplications of Very Small Matrices. Parallel Comput. 2019, 81, 1–21. [Google Scholar] [CrossRef] [Scilit]
- Axelsson, O. Solution of Linear Systems of Equations: Iterative Methods. In Sparse Matrix Techniques; Springer: Berlin/Heidelberg, Germany, 2007; pp. 1–51. [Google Scholar]
- Ghiasvand, S.; Reisizadeh, A.; Alizadeh, M.; Pedarsani, R. Robust Decentralized Learning with Local Updates and Gradient Tracking. IEEE Trans. Netw. 2025, 33, 2036–2048. [Google Scholar] [CrossRef] [Scilit]
- LeCun, Y.; Bengio, Y.; Hinton, G. Deep Learning. Nature 2015, 521, 436–444. [Google Scholar] [CrossRef] [Scilit]
- Santry, D.J. Convolutional Neural Networks. In Demystifying Deep Learning: An Introduction to the Mathematics of Neural Networks; Wiley: Hoboken, NJ, USA, 2024; pp. 111–131. [Google Scholar] [CrossRef] [Scilit]
- Hu, P.; Sun, L.; Hu, C.; Mao, X.; Guo, S.; Wang, J.; Yu, M. Efficient and Performant Transformer Private Inference with Heterogeneous Attention Mechanisms. Appl. Soft Comput. 2025, 176, 113150. [Google Scholar] [CrossRef] [Scilit]
- Kartsev, A.; Malkovsky, S.; Chibisov, A.N. Analysis of Ionicity-Magnetism Competition in 2D-MX3 Halides towards a Low-Dimensional Materials Study Based on GPU-Enabled Computational Systems. Nanomaterials 2021, 11, 2967. [Google Scholar] [CrossRef] [Scilit]
- Andrade, X.; Pemmaraju, C.D.; Kartsev, A.; Xiao, J.; Lindenberg, A.; Rajpurohit, S.; Tan, L.Z.; Ogitsu, T.; Correa, A.A. INQ, a Modern GPU-Accelerated Computational Framework for (Time-Dependent) Density Functional Theory. arXiv 2021, arXiv:2106.03872. [Google Scholar] [CrossRef] [Scilit]
- Shuvo, M.M.H.; Islam, S.K.; Cheng, J.; Morshed, B.I. Efficient Acceleration of Deep Learning Inference on Resource-Constrained Edge Devices: A Review. Proc. IEEE 2023, 111, 42–91. [Google Scholar] [CrossRef] [Scilit]
- Mittal, S.; Vetter, J.S. A Survey of CPU-GPU Heterogeneous Computing Techniques. ACM Comput. Surv. 2015, 47, 1–35. [Google Scholar] [CrossRef] [Scilit]
- Topcuoglu, H.; Hariri, S.; Wu, M.-Y. Performance-Effective and Low-Complexity Task Scheduling for Heterogeneous Computing. IEEE Trans. Parallel Distrib. Syst. 2002, 13, 260–274. [Google Scholar] [CrossRef] [Scilit]
- Stratton, J.A.; Stone, S.S.; Hwu, W.M.W. MCUDA: An Efficient Implementation of CUDA Kernels for Multi-Core CPUs. In Languages and Compilers for Parallel Computing; Springer: Berlin/Heidelberg, Germany, 2008; pp. 16–30. [Google Scholar]
- Gepner, P.; Kowalik, M.F. Multi-Core Processors: New Way to Achieve High System Performance. In International Symposium on Parallel Computing in Electrical Engineering; IEEE: New York, NY, USA, 2006; pp. 9–13. [Google Scholar] [CrossRef] [Scilit]
- Su, X.; Liao, X.; Jiang, H.; Yang, C. SCP: Shared Cache Partitioning for High-Performance GEMM. ACM Trans. Archit. Code Optim. 2018, 15, 43. [Google Scholar] [CrossRef] [Scilit]
- Utrera, G.; Farreras, M.; Fornes, J. Task Packing: Efficient Task Scheduling in Unbalanced Parallel Programs to Maximize CPU Utilization. J. Parallel Distrib. Comput. 2019, 134, 37–49. [Google Scholar] [CrossRef] [Scilit]
- Lavaee, R. The Hardness of Data Packing. ACM SIGPLAN Not. 2016, 51, 232–242. [Google Scholar] [CrossRef] [Scilit]
- Bhattacharjee, A.; Martonosi, M. Inter-Core Cooperative TLB for Chip Multiprocessors. ACM SIGPLAN Not. 2010, 45, 359–370. [Google Scholar] [CrossRef] [Scilit]
- Rodríguez, A.; Navarro, A.; Asenjo, R.; Corbera, F.; Gran, R.; Suárez, D.; Nunez-Yanez, J. Exploring Heterogeneous Scheduling for Edge Computing with CPU and FPGA MPSoCs. J. Syst. Archit. 2019, 98, 27–40. [Google Scholar] [CrossRef] [Scilit]
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, L.; Gomez, A.N.; Kaiser, Ł.; Polosukhin, I. Attention Is All You Need. Adv. Neural Inf. Process. Syst. 2017, 30, 5998–6008. [Google Scholar]
- Tandon, A.; Manju, K.M.; Patel, S. A New VMP Approach Based on CPU and Memory Using Bin Packing. In 2024 IEEE Pune Section International Conference (PuneCon); IEEE: New York, NY, USA, 2024; pp. 1–6. [Google Scholar] [CrossRef] [Scilit]
- Hestness, J.; Keckler, S.W.; Wood, D.A. A Comparative Analysis of Microarchitecture Effects on CPU and GPU Memory System Behavior. In 2014 IEEE International Symposium on Workload Characterization (IISWC); IEEE: New York, NY, USA, 2014; pp. 150–160. [Google Scholar]
- Liu, H.; Shi, S.; Wang, X.; Jiang, Z.L.; Chen, Q. Performance Analysis and Optimizations of Matrix Multiplications on ARMv8 Processors. In 2024 Design, Automation & Test in Europe Conference & Exhibition (DATE); IEEE: New York, NY, USA, 2024; pp. 1–6. [Google Scholar]
- Heinecke, A.; Henry, G.; Hutchinson, M.; Pabst, H. LIBXSMM: Accelerating Small Matrix Multiplications by Runtime Code Generation. In SC ’16: Proceedings of the International Conference for High Performance Computing, Networking, Storage and Analysis; IEEE: New York, NY, USA, 2016; pp. 981–991. [Google Scholar] [CrossRef] [Scilit]
- Kunpeng Math Library (KML) Developer Guide. Huawei Technologies Co., Ltd. Available online: https://support.huawei.com/enterprise/zh/doc/EDOC1100283144/8dea3eb?utm_source=chatgpt.com (accessed on 20 March 2026).
- Zhang, W.; Jiang, Z.; Chen, Z.; Xiao, N.; Ou, Y. NUMA-Aware DGEMM Based on 64-Bit ARMv8 Multicore Processors Architecture. Electronics 2021, 10, 1984. [Google Scholar] [CrossRef] [Scilit]
- Yu, X.; Ma, H.; Qu, Z.; Fang, J.; Liu, W. NUMA-Aware Optimization of Sparse Matrix–Vector Multiplication on ARMv8-Based Many-Core Architectures. In Network and Parallel Computing: 17th IFIP WG 10.3 International Conference; ACM: New York, NY, USA, 2020; pp. 231–242. [Google Scholar]
- Zheng, J.; Jiang, J.; Du, J.; Huang, D.; Lu, Y. Optimizing Massively Parallel Sparse Matrix Computing on ARM Many-Core Processor. Parallel Comput. 2023, 117, 103035. [Google Scholar] [CrossRef] [Scilit]
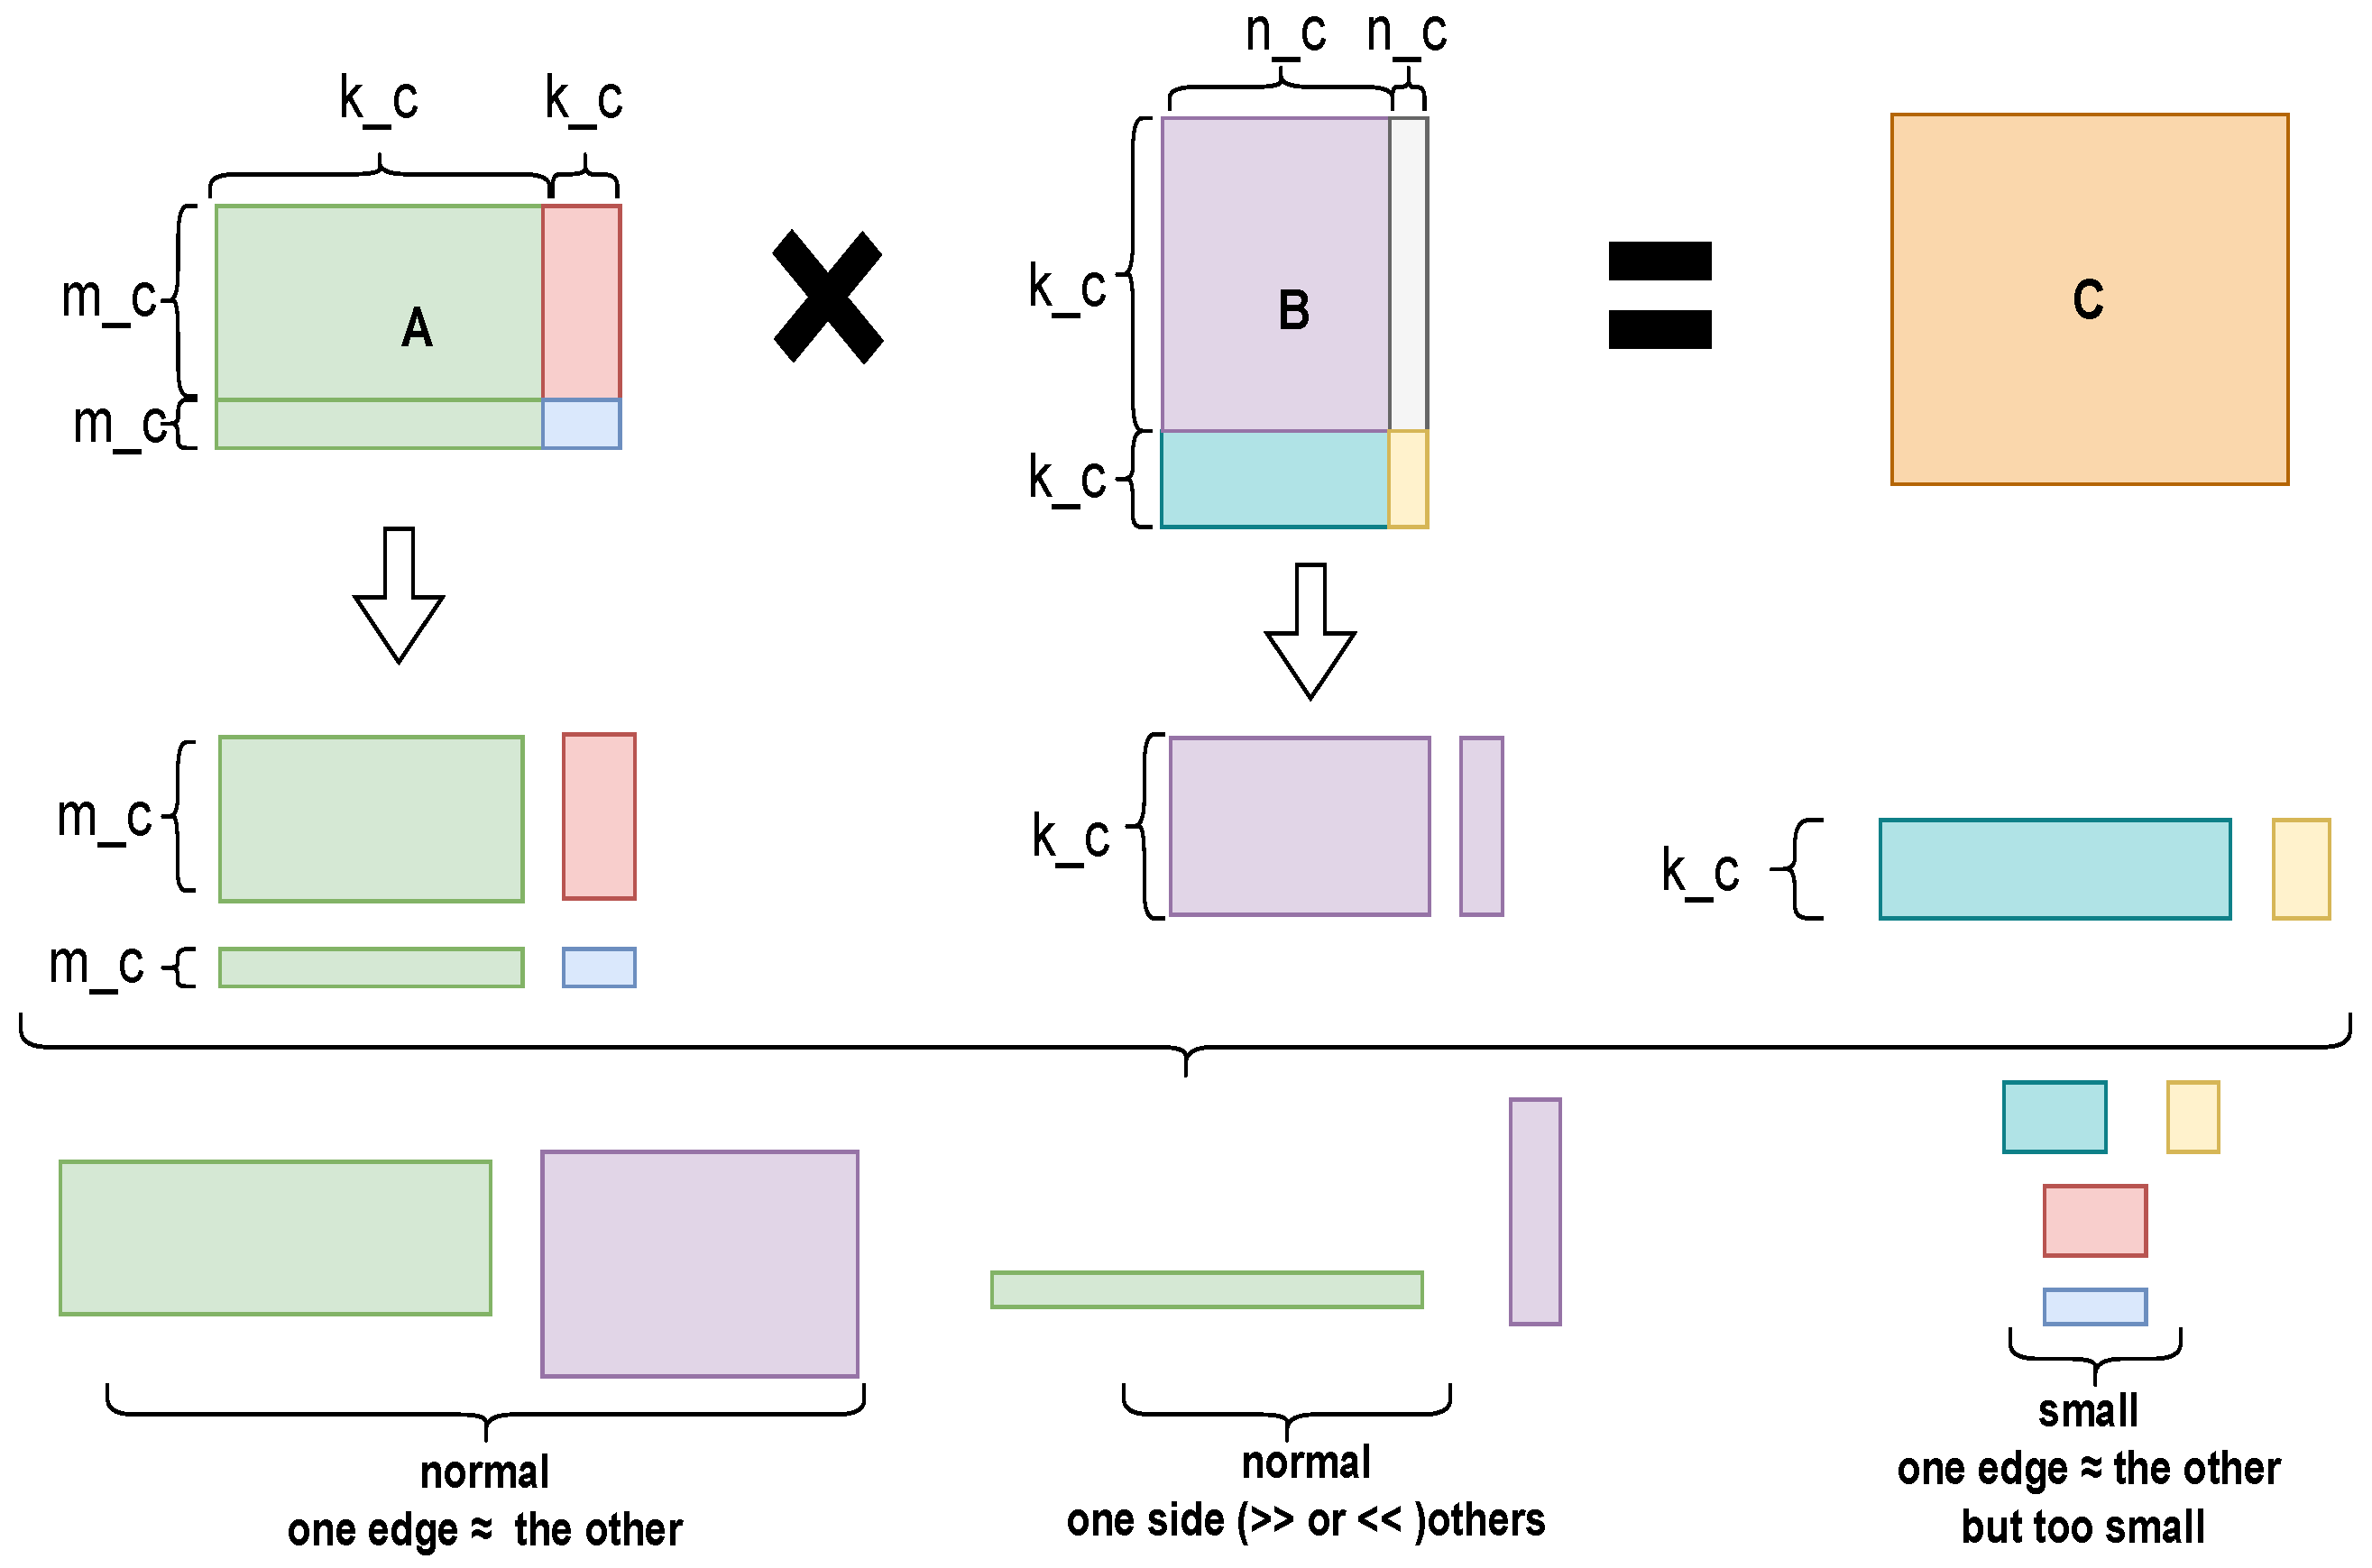

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.