


Highlights
What are the main findings?
- •
- This study proposes DS-UNet for fine-grained highway region segmentation from UAV perspective, integrating a Dilated-Global Context Block (DGCBlock) and a Semantic-Guided Channel-Spatial Attention (SGCSA) module to enhance multi-scale context modeling, semantic-guided feature reconstruction and background interference suppression.
- •
- On the UAVRR3K dataset, DS-UNet achieves 97.31% F1 and 94.76% Road-class IoU, outperforming representative CNN- and Transformer-based segmentation models. Moreover, the proposed boundary-weighted BCE-Dice hybrid loss (BWD) further increases Boundary Recall to 77.88%, improving the completeness of road-boundary prediction.
What are the implications of the main findings?
- •
- The proposed method effectively improves highway region integrity and boundary completeness under challenging UAV scenarios involving vehicle occlusion, shadow interference, viewpoint variations and complex roadside backgrounds.
- •
- The proposed multi-scale context modeling, semantic-guided feature calibration and boundary-aware supervision can also be extended to other UAV-based or remote-sensing fine-grained region segmentation tasks with complex backgrounds and ambiguous boundaries.
Abstract
Accurate highway region segmentation is essential for road inspection and traffic scene understanding. However, complex backgrounds, viewpoint variations, occlusions and shadows often lead to incomplete segmentation of road regions and inaccurate boundary predictions. This paper proposes an improved UNet model, DS-UNet, for fine-grained highway region segmentation from UAV imagery. A Dilated-Global Context Block (DGCBlock) is embedded within the encoder to fuse multi-scale dilated features with global context information, enhancing the feature representation of continuous road structures. Meanwhile, a Semantic-Guided Channel-Spatial Attention (SGCSA) module is devised for the decoder, in which high-level semantic features guide channel-spatial feature recalibration to boost fine-detail reconstruction and suppress background interference. In addition, a boundary-weighted BCE-Dice hybrid loss (BWD) is proposed to strengthen supervision for road boundary pixels. To evaluate the model’s performance, this paper constructed the UAVRR3K dataset consisting of 3000 highway region images captured under diverse UAV perspectives and complex road scenarios. Experimental results show that DS-UNet achieves an F1 of 97.31% and a Road-class IoU of 94.76%, outperforming comparative models. Benefiting from the proposed BWD loss, boundary recall reaches 77.88%. These results verify that our method effectively enhances road region integrity and boundary completeness, offering reliable technical support for UAV-based intelligent highway inspection.
1. Introduction
Highways constitute an important component of regional networks and play a critical role in long-distance freight and passenger transport [1]. Video-based object detection and semantic segmentation have become mainstream techniques for traffic monitoring [2]. In road-scene semantic segmentation, accurate extraction of highway pavement regions provides essential spatial information for traffic-state perception, pavement distress inspection and emergency response [3]. Currently, the visual data used for highway monitoring are primarily acquired from vehicle-mounted cameras and roadside surveillance cameras. These conventional monitoring approaches usually suffer from high detection costs, limited coverage, and low inspection efficiency in practical applications, rendering them inadequate for the operational requirements of highways [4,5].
Owing to the advantages in wide imaging coverage, high spatial resolution, flexible payload deployment and strong maneuverability, the unmanned aerial vehicle (UAV) has been increasingly adopted as a mobile sensing platform for traffic monitoring [6]. By carrying high-resolution imaging devices, UAVs are capable of acquiring rich image data from low-altitude viewpoints. From these data, critical information including road geometry and pavement conditions can be further extracted, which provides technical support for highway operation-management and infrastructure maintenance [7,8]. However, accurate extraction of highway regions using images captured by UAVs in flight remains particularly challenging due to complex road environments, varied road structures, occlusions from vehicles and roadside facilities, shadow interference and changing viewpoints [9].
Traditional image-based road region extraction methods mainly rely on handcrafted features such as color, texture and geometric information to extract road regions [10]. Under relatively simple conditions such as clearly defined road structures and stable illumination, these methods can achieve high processing efficiency and relatively accurate road region delineation. However, they exhibit poor robustness when processing UAV-acquired images in complex road environments due to shadow interference, blurred boundaries and viewpoint variations [11]. With the development of deep learning, semantic segmentation methods have become a mainstream approach for road region extraction owing to their strong capability in learning high-level semantic and contextual features [12]. Nevertheless, existing models still exhibit limitations in fine-grained feature preservation and long-range dependency modeling when confronted with the aforementioned challenges in complex UAV-view scenarios [13,14].
Among existing semantic segmentation frameworks, UNet is well suited to UAV-based highway region segmentation owing to its efficient encoder–decoder architecture and skip connections. However, its standard convolutional encoder remains limited in capturing multi-scale structures and global contextual information. Meanwhile, the direct fusion of low-level and high-level features in the decoder may lead to insufficient semantic guidance for fine-detail recovery. Besides, existing loss functions primarily emphasize the overall classification accuracy of road regions and provide limited supervision for boundary pixels, making it difficult to accurately preserve the geometric structure and boundary details of road regions [15,16,17].
From the low-altitude perspective of UAVs, large-scale variations due to altitude changes, occlusions and perspective distortion can lead to blurred boundaries, fragmented and incomplete detection of road regions. Relying merely on single-scale semantic information and conventional region-level supervision cannot adequately characterize the continuous spatial structure and fine boundary features of highway regions. To address this issue, this study proposes an improved UNet-based semantic segmentation framework combined with a boundary-weighted loss function BWD loss to boost the highway region segmentation performance. The main contributions are summarized as follows:
- •
- Based on the UNet architecture, a Dilated-Global Context Block (DGCBlock) is proposed to enhance encoder feature representation. It constructs parallel multi-scale dilated convolution branches and a global context branch, enabling the network to extract local road details and continuous road structural features simultaneously. It can enhance the continuous feature representation of highway region areas and contextual reasoning ability under complex backgrounds, significantly improving road region segmentation performance from the UAV perspective.
- •
- A Semantic-Guided Channel-Spatial Attention (SGCSA) module is proposed to boost feature fusion and fine-detail reconstruction within the decoder. This module leverages upsampled high-level semantic features to drive channel-spatial attention, enabling adaptive refinement of fused features throughout the decoding stage. This semantic-guided fusion strategy enhances the feature representation of road areas and improves the model’s segmentation robustness under vehicle occlusion, shadow interference, and complex backgrounds.
- •
- A boundary-weighted BCE-Dice (BWD) hybrid loss function is proposed to strengthen supervisory constraints on highway-boundary pixels during model training. By constructing a boundary weight map derived from the ground-truth mask, BWD imposes higher loss weights on boundary pixels within both the BCE and Dice loss terms. This boundary-aware supervision enables finer-grained delineation of highway boundaries while preserving the overall segmentation performance of road areas.
The remainder of this paper is organized as follows. Section 2 reviews related research. Section 3 elaborates on the proposed DS-UNet network architecture and the BWD loss function. Section 4 verifies and analyzes the effectiveness of the proposed method via experiments. Section 5 concludes this paper and prospects future research directions.
2. Related Work
In intelligent transportation systems, road region extraction serves as a vital component for traffic scene perception. Existing road region extraction methods can be broadly divided into two categories: traditional image processing-based methods and deep learning-based methods. The related work is organized as follows:
2.1. Traditional Image Processing Methods
Traditional image processing-based methods predominantly rely on heuristic algorithms derived from prior knowledge or specific expertise. These methods enable the rapid extraction of candidate road regions based on discrepancies between road areas and backgrounds in RGB information, edge textures and geometric shapes. According to the adopted features and processing strategies, existing methods can be broadly categorized into pixel difference-based methods, edge and linear structure-based methods, and region/object-based methods [18].
Pixel difference-based methods extract road regions by exploiting spectral feature discrepancies between road surfaces and surrounding backgrounds, typically through threshold segmentation, cluster analysis and morphological operations. For example, authors in [19] adopt an adaptive threshold method to separate candidate road regions from high-resolution remote sensing images. Combined with morphological filtering, the method suppresses spurious noise regions and connects fragmented road segments, yielding relatively contiguous road regions. Besides, authors in [20,21] introduce multi-scale line segment orientation histograms, sector descriptors and multi-feature combination strategies to strengthen the spectral, textural and morphological representation of candidate road regions. Such methods generally feature simple processing pipelines and low computational costs. Nevertheless, when fixed thresholds or local grayscale features cannot reliably distinguish road and non-road regions, problems including false detections, missed detections and region fractures tend to occur.
Edge and linear structure-based methods further leverage the directionality and continuity of road boundaries and lane markings for road detection [22]. The authors in [23] adopt Gabor filtering and hysteresis thresholding to obtain initial road responses. Afterwards, shape screening, morphological processing and tensor voting are combined to reconstruct broken road centerlines affected by occlusions. Authors in [24] present an effective semiautomatic road delineation method based on geodesic distance field (GDF) and piecewise polygon fitting. Such methods exhibit certain advantages for straight or gently curved roads with clear boundaries and stable orientations. However, edge responses are prone to fracture when roads are occluded by roadside facilities. Meanwhile, quasi-linear structures may also generate strong responses, leading to the false extraction of spurious road regions.
To address the limited adaptability of single traditional image processing methods in complex scenarios, several studies further introduce region-based or object-based approaches to improve road region extraction performance. Authors in [25] present a novel object-based automatic road extraction method. Candidate objects were generated via image segmentation, and object feature screening, active contours and tensor voting were combined to mitigate road gaps and enhance the continuity of road centerlines. Authors in [26] integrate fuzzy object-based analysis and ant colony optimization. Comprehensive utilization of object spectral, spatial and texture features improve road recognition and network optimization for complex high-resolution remote sensing images. Furthermore, road extraction methods using probabilistic structural modeling and topological constraints are gradually applied to road network recognition. Joint characterization of local road geometric features, spectral information and network connectivity alleviates the influence of local noise and road fractures on the integrity and continuity of extraction results [27,28]. Overall, compared with pixel-wise and edge-based methods, region-based or object-based methods can better exploit spatial context and road topological relationships. Nevertheless, such methods still heavily rely on image quality, handcrafted feature design and complicated rule constraints. When road areas are occluded by roadside objects or disturbed by strong background clutter, these approaches struggle to stably extract intact road regions.
2.2. Deep Learning-Based Methods
With the development of deep learning techniques, CNN-based semantic segmentation methods can automatically learn deep semantic features of roads through end-to-end training, and have gradually become a mainstream approach for road region extraction. Early studies mainly adopted classic semantic segmentation networks such as FCN, SegNet and UNet. These networks realize pixel-level recognition of road regions by learning hierarchical semantic features of images and recovering spatial information [29,30,31]. Based on the above foundation, several works cascade multiple lightweight UNets or develop spatially enhanced densely connected UNet architectures to improve the learning performance of road features [32,33]. Compared with traditional image processing methods, such networks significantly improve feature learning performance under complex road scenarios. Nevertheless, local convolutions exhibit limited capacity in modeling long-range contextual relationships, and successive downsampling tends to result in the loss of edge textures and fine-grained spatial information. Consequently, basic convolutional networks struggle to balance local details and global semantics of road regions, and the segmentation results may still suffer from blurred boundaries, region missing and false recognition of background areas.
To address the insufficient scale adaptability of basic convolutional networks, relevant studies further improve road segmentation networks from the perspectives of multi-scale feature extraction, receptive field expansion and spatial detail recovery. Authors in [34] propose a deep learning model, which is called the dense-global-residual network that reduces the loss of spatial information and enhances context awareness. Authors in [12] propose an enhanced deep neural network model termed dual-decoder-Unet (DDU-Net). Motivated by the UNet model, a small decoder is added to form a dual-decoder structure for more detailed features. For UAV road scenario, the authors in [35] propose an enhanced UNet for real-road scenario extraction and 3D modeling. It improves the automatic extraction performance of road regions in UAV imagery via context aggregation and structural optimization. In summary, these studies mitigate the problems of single feature scale and insufficient detail recovery of baseline networks to a certain extent. Nevertheless, features at different layers exhibit distinct discrepancies in spatial resolution and receptive field. Simple concatenation or element-wise fusion cannot achieve sufficient cross-layer interaction, and the model fails to fully exploit the synergy between shallow edge details and deep semantic information.
On the basis of multi-scale feature modeling, relevant studies further boost the representation capability of models from the perspectives of road structural relationships, global context and utilization of supervision information. Authors in [36] propose SOC-RoadNet. It constructs weak supervision labels using open road maps, and improves the performance of large-scale road extraction via structural consistency and directional consistency constraints, reducing the model’s reliance on fine pixel-level annotations. In recent years, Transformer and its variants have also been gradually introduced into the road extraction task. The self-attention mechanism establishes long-range correlations between different spatial positions, enhancing the model’s ability to model global scene information and the overall structure of roads [37]. Such methods promote the evolution of road extraction networks from local feature learning toward collaborative modeling of structural relations and global semantics. Nevertheless, multi-task methods usually rely on additional annotations of centerlines or edges. Weakly supervised approaches are susceptible to the quality of initial labels and pseudo-labels. Meanwhile, Transformer-based methods impose higher requirements on data volume and computing resources.
In addition to improvements in network architecture, some studies have sought to enhance the performance of road region segmentation models by optimizing loss functions. Authors in [38] introduce an edge-aided detection task and weight-balanced loss into the road extraction network. By increasing the supervision weights of edge regions and hard samples during training, the issues of blurred road boundaries and missed detection of small-scale roads are alleviated. For slender continuous targets such as roads, blood vessels and cracks, relevant studies have further proposed various topology-preserving losses [39,40,41]. By introducing constraints on neighborhood relations, centerlines and topological structures, such methods effectively strengthen the structural continuity of slender objects.
Recent studies have explored adapting self-supervised vision foundation models to remote sensing segmentation. Authors in [42] propose HyperR3SNet, combining multiscale cross-attention, a matrix-factorized prediction head and a hyperbolic pixel-level loss to capture latent interclass relationships. Besides, authors in [43] introduce MsRE, which uses learnable tokens to interact with multiscale features for parameter-efficient adaptation and feature refinement. Conceptually, these developments share an emphasis on scale-aware representation and feature refinement with DGCBlock’s multiscale context aggregation and SGCSA’s semantic-guided feature calibration. However, hyperbolic class-relation supervision concerns the geometry of semantic representations, whereas BWD assigns higher loss weights to spatial boundary pixels. For binary road–background segmentation, multiscale modeling and semantic refinement remain relevant, while the benefits of hierarchical class-relation modeling require task-specific validation. DS-UNet addresses these representation and boundary-supervision requirements within a UNet framework trained from scratch.
Overall, deep learning-based road extraction has evolved from local convolutional feature learning toward multi-scale fusion, global context modeling, and loss-function optimization. However, UAV imagery remains challenging due to varying flight altitudes and viewing angles, vehicle occlusion, shadows and complex roadside backgrounds. Existing models often struggle to simultaneously preserve complete road regions and fine boundary details, while insufficiently exploiting multi-scale features, long-range dependencies and cross-layer semantic relationships. Moreover, conventional region-level losses provide limited supervision for road boundaries. To address these limitations, this paper proposes DS-UNet. In the encoder, DGCBlock combines parallel multi-scale dilated convolutions with global context modeling to enhance local details and long-range semantic dependencies. In the decoder, SGCSA uses high-level semantic features to guide channel-spatial feature calibration, strengthening road responses while suppressing background interference. Furthermore, a boundary-weighted BCE-Dice loss, termed BWD, enhances boundary supervision and improves contour recovery. The proposed architecture and loss function are detailed in the following section.
3. Methods
3.1. DS-UNet Model
Based on the UNet encoder-decoder architecture, the DS-UNet for detailed segmentation of road regions in low-altitude UAV images is proposed. The architecture is illustrated in Figure 1.
Figure 1.
DS-UNet road region segmentation model.
Referring to Figure 1, the proposed DS-UNet architecture consists of four encoder layers, one bottleneck layer, four decoder layers and multi-level skip connections. In the encoding stage, each encoder layer comprises two cascaded modules, namely DoubleConv and DGCBlock. The DoubleConv first extracts spatial detailed features of road regions. Subsequently, the embedded DGCBlock further captures global semantic information and long-range spatial dependencies of road regions. The bottleneck layer adopts an identical operational structure to that of the encoder layer. After each encoder layer, the feature maps are downsampled via max-pooling operation. In the decoding stage, bilinear interpolation is used to upsample decoder features to higher spatial resolutions. The upsampled decoder features are concatenated with corresponding encoder features via skip connections, followed by a DoubleConv module to reconstruct fine-grained local detail. Subsequently, the SGCSA module leverages upsampled semantic features as guidance to perform channel and spatial attention calibration on decoder features, enhancing road region responses while suppressing irrelevant background interference. Finally, a 1 × 1 convolution is applied to produce the road regions prediction map.
3.1.1. Dilated-Global Context Block
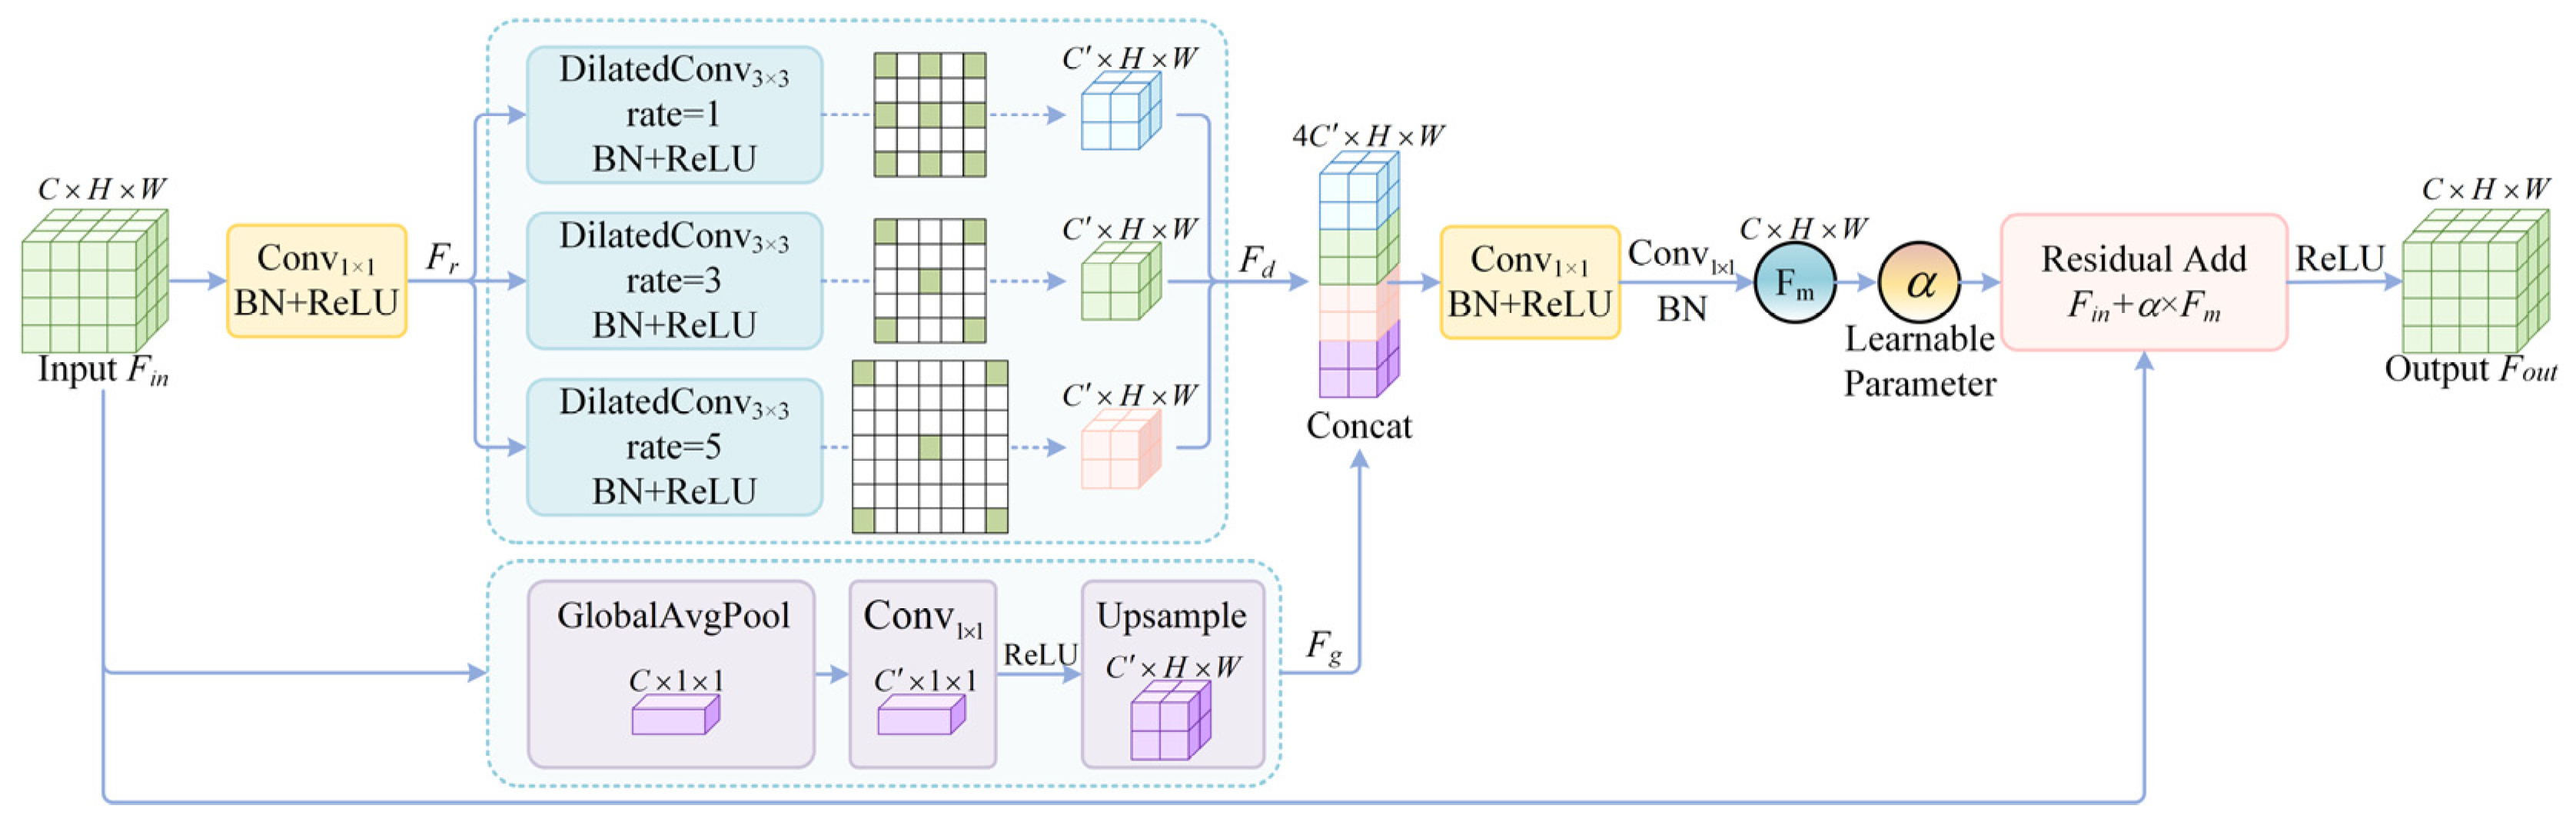
The Dilated-Global Context Block (DGCBlock) consists of a multi-scale dilated convolution branch and a global context branch, as illustrated in Figure 2. This module fuses long range dependencies captured by the two branches at different scales, thereby enhancing the model’s capacity to exploit global contextual information. By introducing learnable scaling parameters, the fused context-enhanced features are further residually connected with the original input features. The DGCBlock is illustrated in Figure 2.
Figure 2.
Schematics of the DGCBlock.
As shown in Figure 2, the input feature Fin ∈ RC×H×W first undergoes a 1 × 1 convolution followed by batch normalization (BN) and ReLU activation to perform channel dimension reduction, yielding dimension-reduced feature maps, . The channel reduction process is expressed by Equation (1).
The channel number C′ of dimension-reduced feature maps is jointly determined by the dimension-reduction ratio and the minimum channel constraint, which guarantees that sufficient feature representation capability is preserved for shallow layers. The C′ is denoted as Equation (2).
Subsequently, the dimension-reduced feature map Fr is fed into multiple parallel dilated convolution branches with different dilation rates. In this work, dilation rates of 1, 3 and 5 are employed to capture the dependencies of road regions at various scales. The output dilated convolution feature can be expressed by Equation (3).
Besides, the DGCBlock further integrates a global context branch to capture broader image-level semantic information. First, the input feature Fin ∈ RC×H×W undergoes adaptive global average pooling, which compresses its spatial dimensions into a global channel descriptor with a spatial size of 1 × 1. Subsequently, a 1 × 1 convolution is applied to perform nonlinear mapping and channel compression on this descriptor. Finally, bilinear interpolation is adopted to upsample the derived global semantic feature back to the original spatial size H × W. This operation compresses channels to C′, enabling the model to perceive global semantic distributions and preserve smooth global context semantics, while supporting channel-wise concatenation with local context features from the multi-scale dilated convolution branches. The output global context feature Fg is expressed by Equation (4).
Subsequently, dilated convolution feature and global context feature are concatenated along the channel dimension. Two successive 1 × 1 convolutions are then applied to obtain the preliminary enhanced feature Fm. This process is expressed by Equation (5).
To stabilize network training and mitigate excessive interference to the original features, a learnable scaling parameter α is introduced after obtaining the enhanced features. Each DGCBlock has its own scalar coefficient, initialized to 0.1 and jointly optimized with the network parameters. The enhanced features are multiplied with α, and the result is added to the original input feature Fin via residual connection. Finally, the output feature Fout is obtained after ReLU activation, as expressed by Equation (6).
3.1.2. Semantic-Guided Channel-Spatial Attention Module
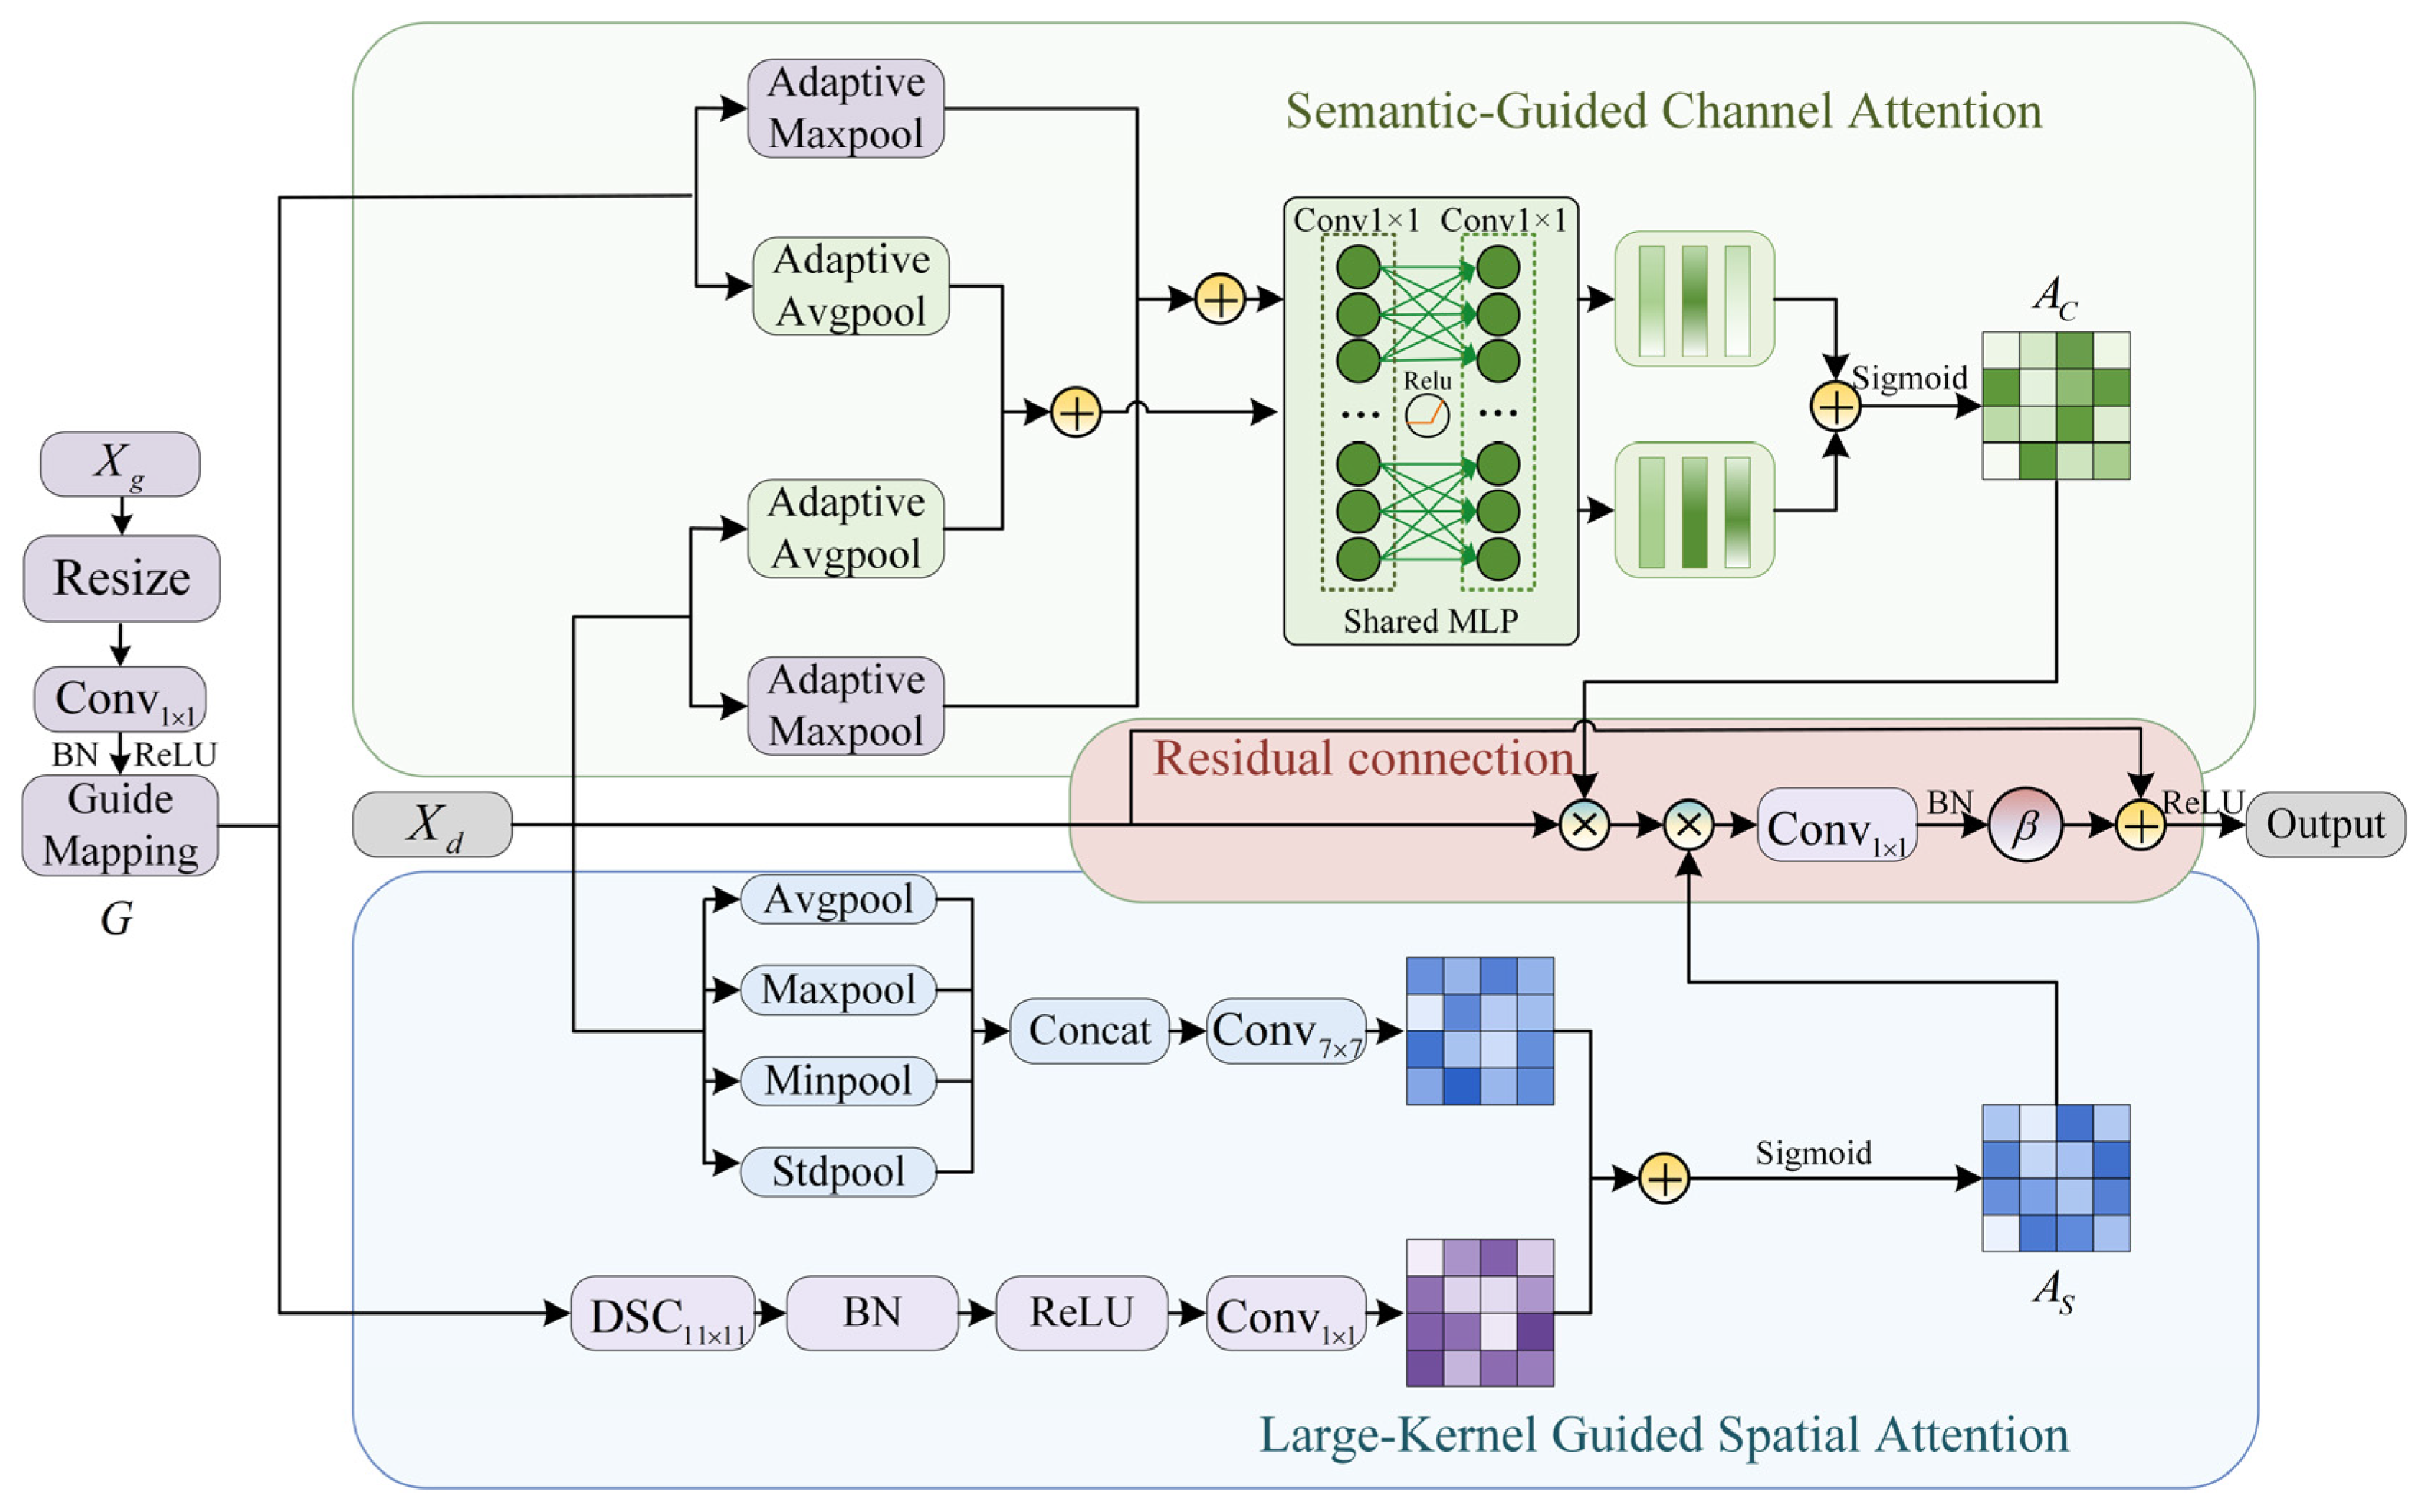
To further guarantee semantic consistency of road regions and enable the progressive recovery of detailed information, a Semantic-Guided Channel-Spatial Attention (SGCSA) module is incorporated in the decoding stage, as shown in Figure 3.
Figure 3.
Schematics of the Semantic-Guided Channel-Spatial Attention.
As shown in Figure 3, the SGCSA module consists of a semantic-guided channel attention branch, a large-kernel semantic-guided spatial attention branch and a residual connection. Let Xd denote the decoder feature reconstructed via upsampling, skip connection concatenation and DoubleConv at the current decoding stage, and Xg represent the corresponding high-level semantic guidance feature. Consistent with the guidance path in Figure 1, Xg denotes the upsampled incoming high-level feature before this concatenation and reconstruction. In this paper, Xg first undergoes size alignment to guarantee that the high-level semantic guidance feature matches the current decoder feature in both spatial size and channel dimension. Channel mapping is subsequently performed via 1 × 1 convolution followed by BN and ReLU activation, yielding the semantic guidance feature G. This process is expressed by Equation (7).
In Equation (7), Resize denotes the spatial size alignment of semantic features. Specifically, bilinear interpolation is adopted to align the spatial size of Xg with Xd. A 1 × 1 convolution is then utilized to match the channel number of Xg to Xd. The resulting semantic guidance feature G exhibits exactly the same tensor dimensions as the decoder feature Xd, thereby enabling its integration into the subsequent calculations of channel attention and spatial attention.
In the semantic-guided channel attention branch, global average pooling and maximum pooling are separately applied to the decoder feature Xd and the semantic guidance feature G to obtain channel-wise global descriptors. In this stage, average pooling characterizes the global response of each channel, while maximum pooling highlights salient semantic information. This process is expressed by Equation (8).
To exploit high-level semantics for constraining the channel selection of decoder features, element-wise addition is performed between the matched average-pooled and max-pooled descriptors of the decoder feature and the semantic guidance feature. The two fused descriptors are processed by a shared MLP for modeling inter-channel nonlinear dependencies. The summation outputs undergo the Sigmoid activation function to generate the semantic-guided channel attention weight AC, as expressed by Equation (9).
In Equation (9), the shared MLP can be expressed by Equation (10).
In the large-kernel semantic-guided spatial attention branch, the current decoder feature Xd is first calculated along the channel dimension to obtain the mean, maximum, minimum and standard deviation, generating four spatial statistical description maps. The computation is formulated in Equation (11).
In Equation (11), Avgc, Maxc, Minc and Stdc denote the mean, maximum, minimum and standard deviation statistics for the feature map along the channel dimension, respectively. These four statistical operations characterize feature responses from different perspectives to obtain comprehensive spatial descriptive information. It should be pointed out that the aforementioned operations are implemented along the channel dimension. The resulting feature maps are single-channel and maintain unchanged spatial size.
Subsequently, the four spatial statistical maps are concatenated along the channel dimension, and a 7 × 7 convolution is applied to generate the local spatial attention response SM. This procedure can be expressed by Equation (12).
Meanwhile, a large-kernel convolution guidance branch is constructed to further exploit high-level semantic information for guiding the generation of spatial attention. Taking the semantic guidance feature G as input, this branch first adopts an 11 × 11 depthwise convolution to introduce semantic priors with an enlarged receptive field. Following BN and ReLU activation, a 1 × 1 convolution is finally utilized to generate the large-kernel guided spatial response SL, as shown in Equation (13).
The local spatial attention response SM and the large-kernel guided spatial response SL are added element-wise, followed by the Sigmoid activation function to generate the final spatial attention weight AS, as expressed by Equation (14).
After the channel attention weight AC and spatial attention weight AS are obtained, SGCSA sequentially applies them to the decoder feature Xd. First, channel attention adaptively recalibrates the importance of different channels. Subsequently, spatial attention further calibrates the responses at different spatial positions to yield the attention-enhanced feature Xa. This procedure is formulated in Equation (15).
In Equation (15), ⊗ denotes element-wise multiplication.
Finally, the attention-enhanced feature Xa is projected by a 1 × 1 convolution and BN. To prevent the attention enhancement branch from excessively disturbing the original decoder feature in the early training stage, an additional learnable scaling parameter β is introduced in SGCSA. Each SGCSA module has its own scalar coefficient, initialized to 0.1 and jointly optimized with the network parameters. The attention-enhanced feature Xa is proportionally fused with the original decoder feature, and the final output feature of SGCSA is obtained after ReLU activation, as expressed by Equation (16).
3.2. Boundary-Weighted BCE-Dice Hybrid Loss Function
Road region semantic segmentation from the UAV perspective requires accurate identification of the dominant road areas as well as fine-grained characterization of road boundaries. Traditional loss functions are typically optimized in terms of overall region overlap or pixel-wise classification. They impose strong constraints on the dominant road areas while providing relatively weak supervision for boundary pixels. This paper constructs a boundary-weighted binary hybrid loss function BWD to strengthen the model’s focus on road boundary regions during the training phase. The BWD is expressed by Equation (17).
In Equation (17), λ1 and λ2 denote the weight coefficients of boundary-weighted BCE loss LWBCE and boundary-weighted Dice loss LWDice, respectively. Referring to the equation, LWBCE is mainly adopted to improve the classification sensitivity of boundary pixels and reduce missed detection in road-edge regions. Meanwhile, LWDice is utilized to boost the boundary overlap consistency between predicted road regions and the corresponding ground-truth regions.
Specifically, Binary Cross-Entropy (BCE) is a widely adopted pixel-level classification loss function for semantic segmentation tasks. It constrains the pixel-wise discrepancy between predicted probabilities and ground-truth labels, improving the model’s capability to distinguish foreground from background. Let yi ∈ {0,1} denote the ground-truth label of the i-th pixel, pi ∈ [0,1] represent the predicted probability, and N be the total number of pixels. The standard BCE loss LBCE is expressed by Equation (18).
To strengthen the supervision intensity of boundary regions, a boundary weight map is constructed based on the ground-truth road mask. Let M ∈ {0,1}H×W denote the binary ground-truth road mask. Morphological dilation and erosion operations are adopted to approximately extract the road boundary response B, and the detailed process is expressed by Equation (19).
As shown in Equation (19), Dilatek and Erodek denote dilation and erosion operations with kernel size k, respectively. Once the boundary response B is acquired, a new boundary weight W is further defined, as shown in Equation (20).
In Equation (20), ω denotes the boundary enhancement coefficient, which governs the additional supervision strength of boundary regions in the loss function.
The boundary band width is determined by the morphological kernel size k, which defines the spatial extent of the road boundary region under enhanced supervision. The boundary weight ω controls the relative loss weight assigned to boundary pixels compared with road interior pixels. A larger k covers more blurred edge pixels but may introduce background interference, while a higher ω boosts boundary recall but may cause excessive boundary dilation. In this paper, k is set to 7 and ω is set to 4 by experience to balance boundary completeness and segmentation precision.
Based on this weighting mechanism, the standard BCE loss LBCE is extended to the boundary-weighted BCE loss LWBCE, as expressed in Equation (21).
Meanwhile, Dice loss directly optimizes the overlap between predictions and ground-truth, which effectively mitigates class imbalance in semantic segmentation. The standard Dice loss LDice is expressed by Equation (22).
As shown in Equation (22), ε denotes a small constant to avoid division by zero. To further improve the contribution of boundary regions in region overlap optimization, the boundary weight W is incorporated into the Dice loss calculation, resulting in the boundary-weighted Dice loss LWDice, as expressed by Equation (23).
4. Experiments and Discussion
4.1. Experimental Conditions and Real UAV Datasets
In this paper, road images are captured by the DJI M350 UAV platform. The environmental conditions, UAV hardware configurations, flight parameters and computing power configurations are exhibited in Table 1. The original dataset is collected from actual highway scenarios, including multi-lane straight sections, curved sections and merge zones under diverse disturbances such as vehicle occlusion, shadow interference and illumination variations.
Table 1.
Parameters of the experiment.
Based on the aforementioned experimental scenarios and conditions, a separate source video recorded for each combination of road segment and flight altitude were collected using the DJI M350 UAV. Keyframes were extracted from each video at 15-s intervals to reduce temporal redundancy and similarity between consecutive sampled frames. The constructed dataset, named UAVRR3K, contains 3000 road region images with an original resolution of 1920 × 1080 P. UAVRR3K was partitioned into training, validation and test subsets at an 8:1:1 ratio using source videos as the grouping unit. All images originating from the same video were assigned exclusively to one subset, ensuring that the source videos did not overlap across the three subsets. To further reduce scene redundancy across different acquisition records, images depicting repeated road sections or overlapping scenes were manually inspected, and redundant samples were removed. To guarantee fairness and consistency for comparative experiments among different models, all networks are trained and evaluated using images resized to 960 × 540 P. This downsampling strategy without cropping preserves the aspect ratio of original UAV images, effectively reduces computational overhead and retains spatial information from the raw images as much as possible.
Input images were resized to 960 × 540 pixels and normalized to [0, 1]. Symmetric zero-padding was applied to feature maps before each downsampling operation to maintain integer spatial dimensions throughout the encoder-decoder pipeline. During training, horizontal and vertical flips were each applied with a probability of 0.5. Color jitter was performed using brightness, contrast and saturation factors within [0.9, 1.1], together with normalized hue shifts within [−0.1, 0.1]. Random rotations within [−10°, 10°] were also applied to introduce small variations in image orientation. These augmentations were intended to increase the appearance and orientation diversity of the training samples.
DS-UNet was trained from scratch without pretrained backbone weights, and its convolutional weights were initialized using He normal initialization. Optimization was performed using AdamW with an initial learning rate of 1 × 10⁻⁴ and a weight decay of 1 × 10⁻⁴. A ReduceLROnPlateau scheduler monitored the validation loss in minimization mode, with a learning-rate reduction factor of 0.5 and a patience of 20 epochs. Training was conducted for 300 epochs with a batch size of 4. For each run, the checkpoint achieving the highest validation road-class IoU was selected for subsequent inference and evaluation.
For fair comparison, all baseline models were retrained from scratch using the same data augmentation pipeline, optimizer settings, learning-rate schedule, training duration and batch size. Three independent training runs with different random seeds were performed for each experimental configuration. The selected checkpoint from each run was evaluated separately on the test set, and the reported segmentation metrics were calculated as the arithmetic means of the corresponding results across the three runs.
In the experiments, two groups of evaluation metrics are set according to different experimental purposes. For comparative experiments of different semantic segmentation models and ablation experiments of the proposed model, five metrics including Precision (Pr), Recall (Re), F1, Road-class Intersection over Union (IoU) and Pixel Accuracy (PA) are adopted to evaluate the segmentation performance. The calculation formulas for these metrics are given in Equations (24)–(28).
In Equations (24)–(28), TP denotes the number of pixels that are correctly predicted as road regions, FP denotes the number of pixels incorrectly predicted as road regions. FN denotes the number of pixels that are misclassified as background. TN denotes the number of pixels correctly predicted as non-road regions.
The Pr and Re can be used to evaluate the false detections and missed detections, while F1 can assess the comprehensive segmentation performance. The road-class Intersection over Union (IoU) directly measures the region overlap quality between the predicted mask and the ground-truth mask for the road category, and PA reflects the overall pixel-level classification accuracy of the model. Using these five metrics, the performance of different models can be comprehensively evaluated in region completeness and overall segmentation accuracy.
To further evaluate the effectiveness of the boundary-weighted hybrid loss for fine-grained road segmentation, three boundary-oriented metrics, including Boundary F1 (BF1), Boundary Precision (BP) and Boundary Recall (BR), are adopted to supplement the conventional F1, Road-class IoU, Pr and Re metrics.
Let Bp denote the set of boundary pixels extracted from the predicted mask, Bg denote the set of boundary pixels extracted from the ground-truth mask, and τ denote the boundary matching tolerance. A predicted boundary pixel is considered a successful match to the ground-truth boundary if it lies within the τ neighborhood of the ground-truth boundary. Similarly, a ground-truth boundary pixel is considered successfully covered by the predicted boundary if it falls within the τ neighborhood of the predicted boundary. Let Dτ(Bg) and Dτ(Bp) represent the boundary matching regions obtained by expanding the neighborhoods of radius τ for the ground-truth boundary and predicted boundary, respectively. The calculation formulas for BP, BR and BF1 are given in Equations (29)–(31).
As shown in Equations (29)–(31), |·| denotes the number of counted boundary pixels, and ε represents a small constant. In this paper, BP reflects the accuracy of boundary prediction, BR reflects the completeness of boundary prediction. BF1 is the harmonic mean of BP and BR for evaluating the matching quality between predicted boundaries and ground-truth boundaries.
4.2. Ablation Study and Analysis
To verify the effectiveness of the proposed DGCBlock and SGCSA modules for road segmentation under UAV perspective, ablation experiments are implemented based on the traditional UNet framework. Using the data samples from UAVRR3K, the ablation results are presented in Table 2. All configurations in Table 2 are trained using Dice loss to evaluate the architectural contributions of DGCBlock and SGCSA under a common loss objective.
Table 2.
Ablation experiment results (%) of DS-UNet.
The ablation results demonstrate that both the DGCBlock and SGCSA modules can improve the segmentation performance for road regions, and their combination yields the optimal performance.
Specifically, with the incorporation of DGCBlock, the model achieves an F1 of 96.07% and a Road-class IoU of 92.44%. Compared with UNet, the configuration incorporating DGCBlock achieves gains of 6.31 percentage points in road-class IoU and 4.11 percentage points in recall. This demonstrates that DGCBlock strengthens the semantic representation of road regions in the encoder stage via its multi-scale dilated convolution branch and global context branch, enabling the model with enhanced capability to recognize dominant road areas as well as fine boundary structures.
Meanwhile, with the incorporation of the SGCSA module, the model achieves F1 and Road-class IoU values of 95.57% and 91.51%, respectively, yielding obvious improvements compared with UNet. Its Precision reaches 98.11%, which is slightly higher than the result obtained using DGCBlock alone. The observation reveals that the SGCSA module can adaptively calibrate channel and spatial features in the decoder stage by leveraging high level semantic information. This suppresses false positive responses from background regions and improves the discriminative performance of road region prediction.
The fusion of the two modules produces a synergistic effect and makes more pronounced improvements of the metrics. Specifically, the Road-class IoU rises from 86.13 to 94.76 and the F1 increases from 92.55 to 97.31, achieving optimal comprehensive performance. The results demonstrate that DGCBlock strengthens multi-scale contextual awareness within the encoder stage, whereas SGCSA exploits high-level semantic information to guide low-level detail recovery in the decoder stage. Their synergistic interaction enables stable performance improvements in road region segmentation, boundary reconstruction and suppression of background interference.
4.3. Comparative Experiments and Analysis
To evaluate the overall performance of the proposed DS-UNet for semantic segmentation of highway regions using UAV images, comparative experiments are conducted against mainstream semantic segmentation models. These models cover classical encoder–decoder architectures such as UNet and UNet++, a multi-scale context model with atrous convolution, DeepLabv3+, an attention-based model, SA-UNet, a high-resolution representation network, HRNet-W18, and a Transformer-based model, SegFormerB0.
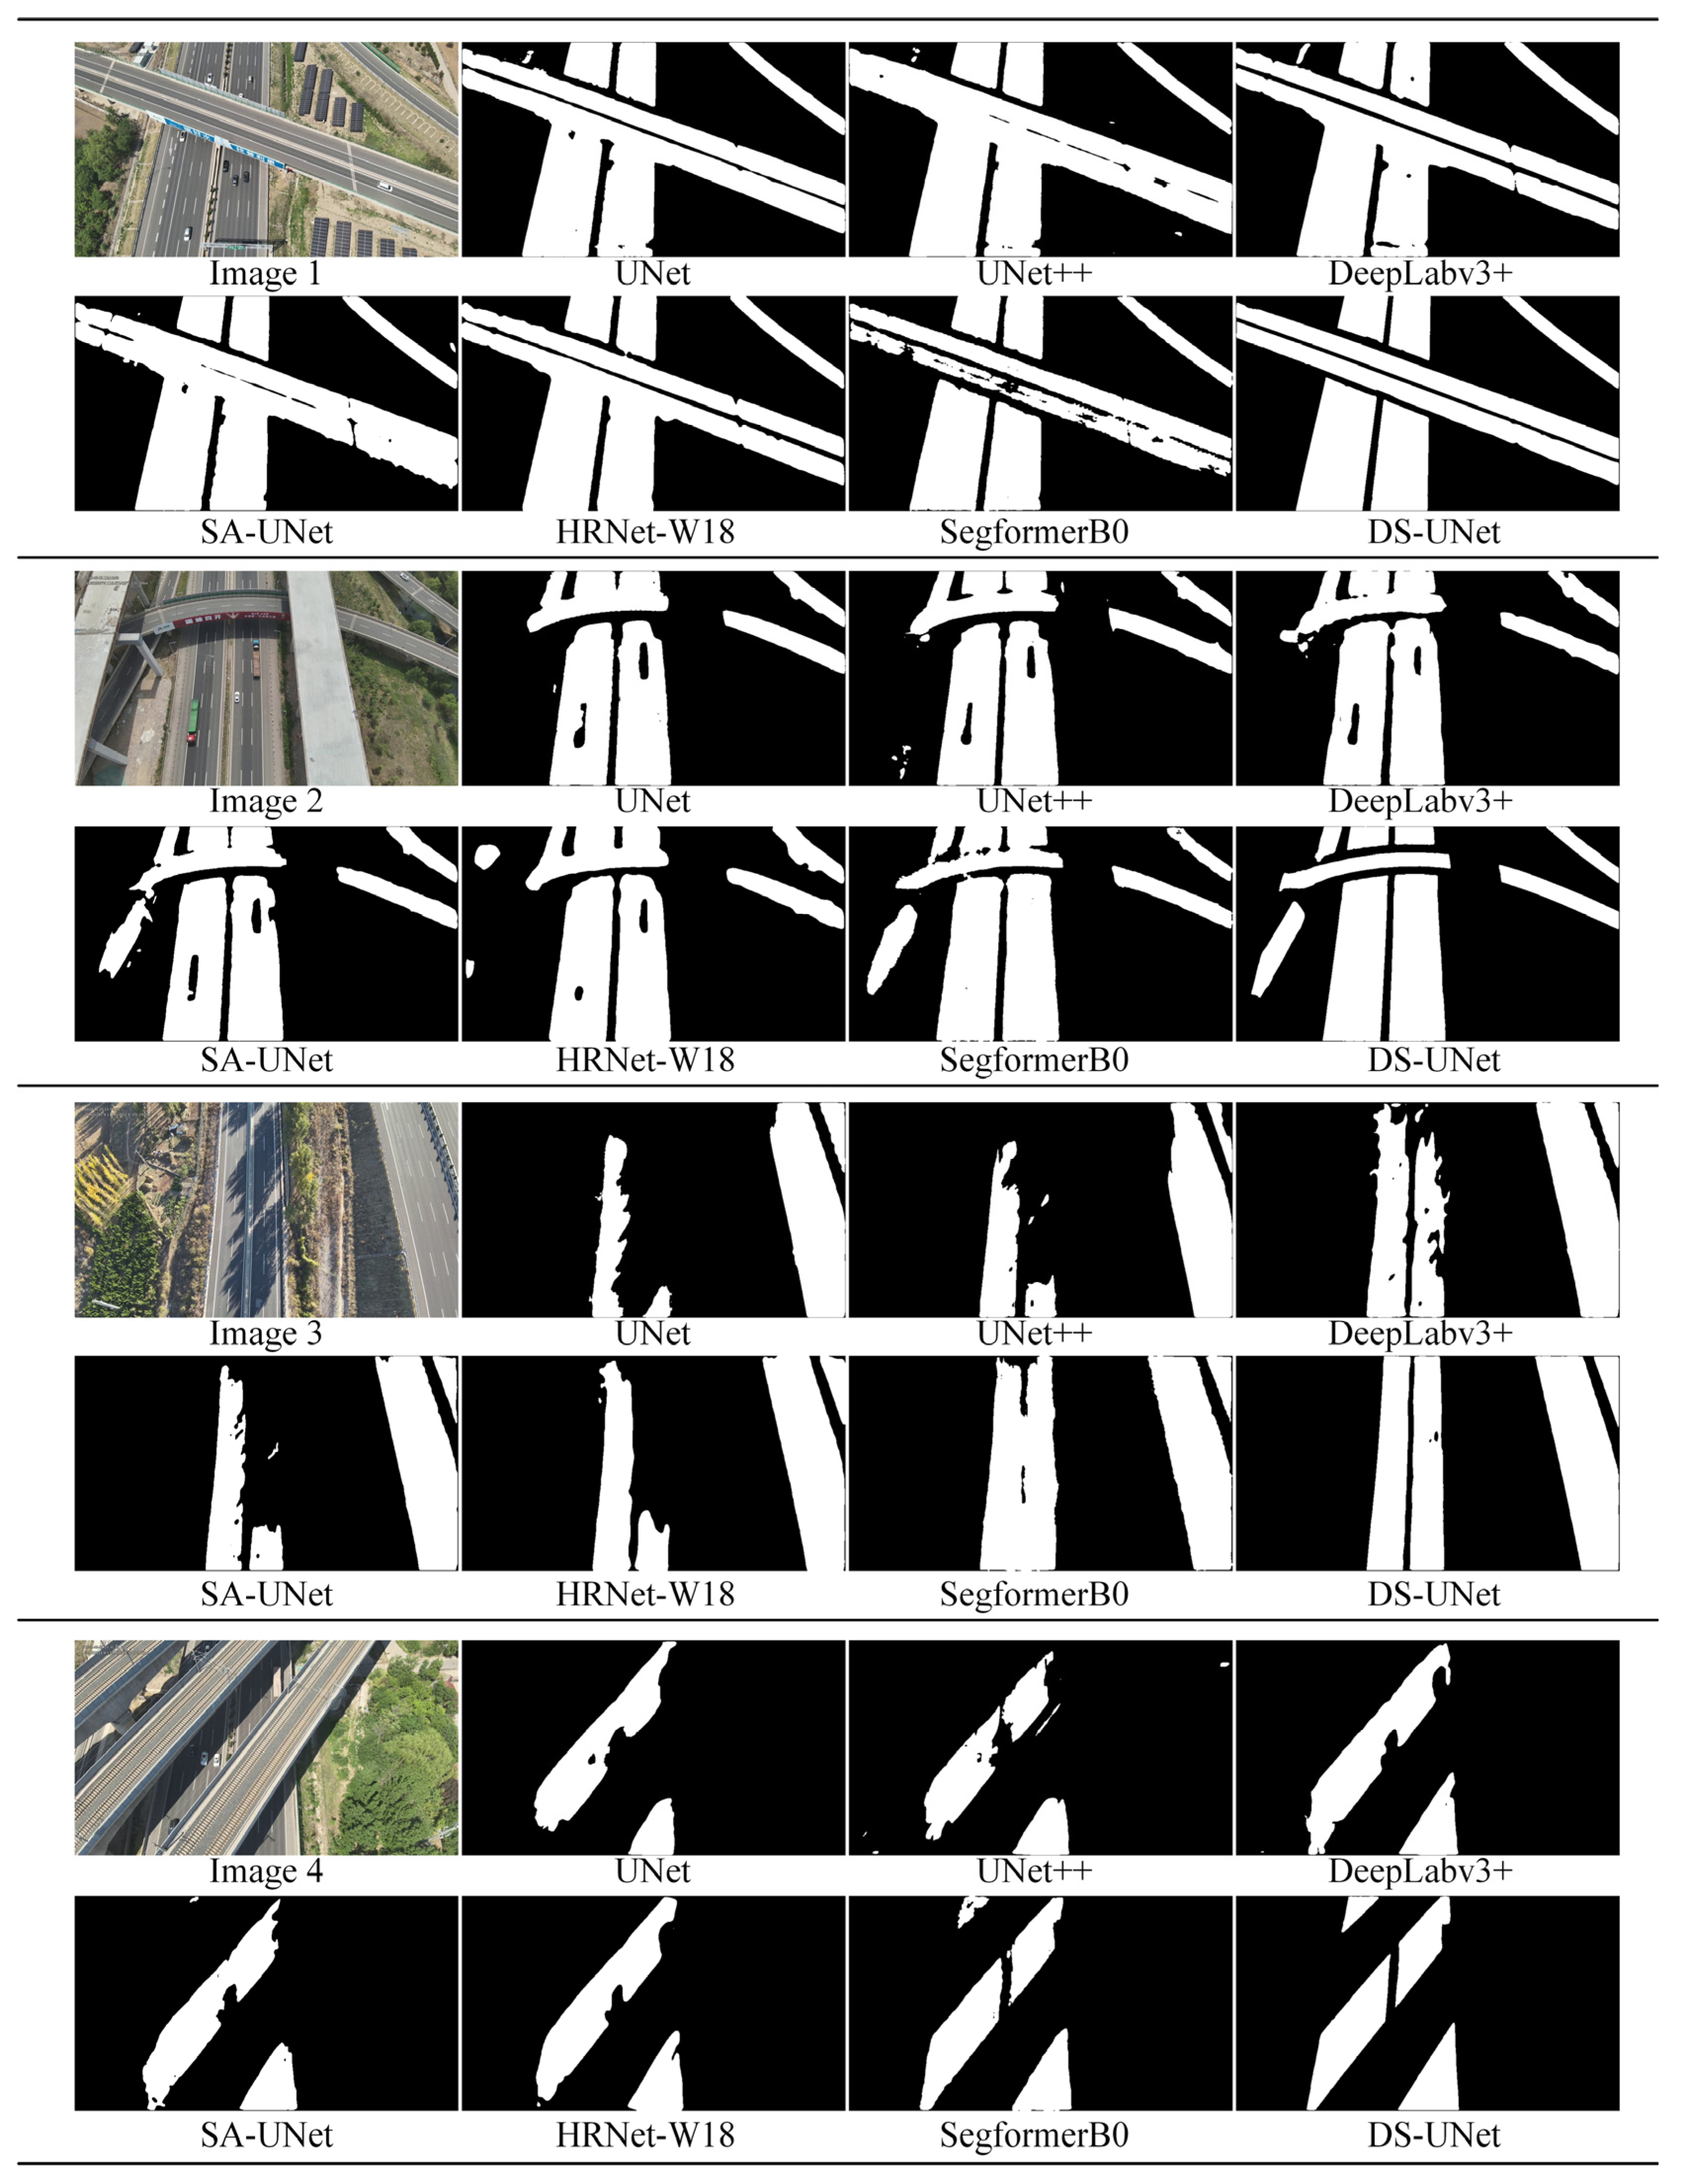
Using the dataset described in Section 4.1, several representative UAV highway images are selected for visual comparison of segmentation results, as shown in Figure 4.
Figure 4.
Road region detection results for different models.
As shown in Figure 4, the proposed DS-UNet model achieves competitive performance in road region integrity, fine-grained boundary delineation and background interference suppression. For the interleaved road scenario shown in Image 1, UNet, UNet++, DeepLabv3+, SA-UNet and HRNet-W18 can roughly extract dominant road areas, yet spiky artifacts and adhesions still exist at road boundaries. Benefiting from the self-attention mechanism embedded in its hierarchical Transformer encoder, SegformerB0 achieves powerful global context modeling and yields relatively complete depiction of the overall road morphology. Nevertheless, hierarchical downsampling induces the loss of fine-grained spatial details, and the decoder exhibits limited capability for recovering local edge textures. As a result, it cannot accurately reconstruct fine internal details within road regions.
For complex road scenarios in Image 2, Image 3 and Image 4 involving vehicle occlusion, shadow occlusion and building occlusion, several competing models exhibit segmentation omissions of varying degrees within road regions. Constrained by the receptive field of local convolutions, UNet and UNet++ tend to yield discontinuous road segments near occluded regions. DeepLabv3+ can recognize certain disturbed areas through dilated convolution and multi-scale context modeling; nevertheless, boundary blurring persists. SA-UNet amplifies feature responses for road regions through the attention mechanism. Nevertheless, it remains vulnerable to interference induced by shadows and roadside textures in complex background scenarios. Although HRNet-W18 preserves high-resolution features, it yields unstable performance in recovering road-edge details and sustaining continuity within occluded regions. In contrast, our model strengthens multi-scale contextual awareness in the encoder via DGCBlock, while SGCSA leverages high-level semantic information to guide low-level detail recovery at the decoder. Therefore, the predictions maintain favorable road region integrity and boundary continuity even under occlusion and complex-background interference.
To further quantitatively assess the road region segmentation performance of different models, Table 3 reports quantitative metrics on the test set for all models trained with the same Dice loss objective.
Table 3.
Experimental results (%) for different semantic segmentation networks. Each gain (↑) is the improvement of DS-UNet over the model listed in that row, calculated as the DS-UNet value minus the corresponding model value in percentage points.
As shown in Table 3, the proposed DS-UNet achieves the best results across F1, Road-class IoU, PA, Re and Pr. Compared with the second-best-performing SegFormerB0, DS-UNet improves these metrics by 0.88, 1.64, 0.62, 1.24 and 0.49 percentage points, respectively, which demonstrates its superior comprehensive segmentation capability. Compared with the baseline U-Net, the corresponding performance gains reach 4.76, 8.63, 3.34, 5.97 and 3.46 percentage points. In particular, the substantial gains in Road-class IoU and Re reveal that DS-UNet generates more complete road region predictions and effectively mitigates segmentation omissions. Meanwhile, the improvement in Pr demonstrates effective suppression of background interference. These results validate that the proposed multi-scale contextual modeling and semantic-guided feature calibration can effectively improve both regional integrity and feature discriminability for highway region segmentation outputs. In practical UAV-based highway inspection, the predicted road mask can be used to delineate the region of interest for subsequent pavement distress detection and traffic monitoring, thereby filtering out irrelevant roadside background interference.
4.4. Comparative Experiments and Analysis Under Different Loss Functions
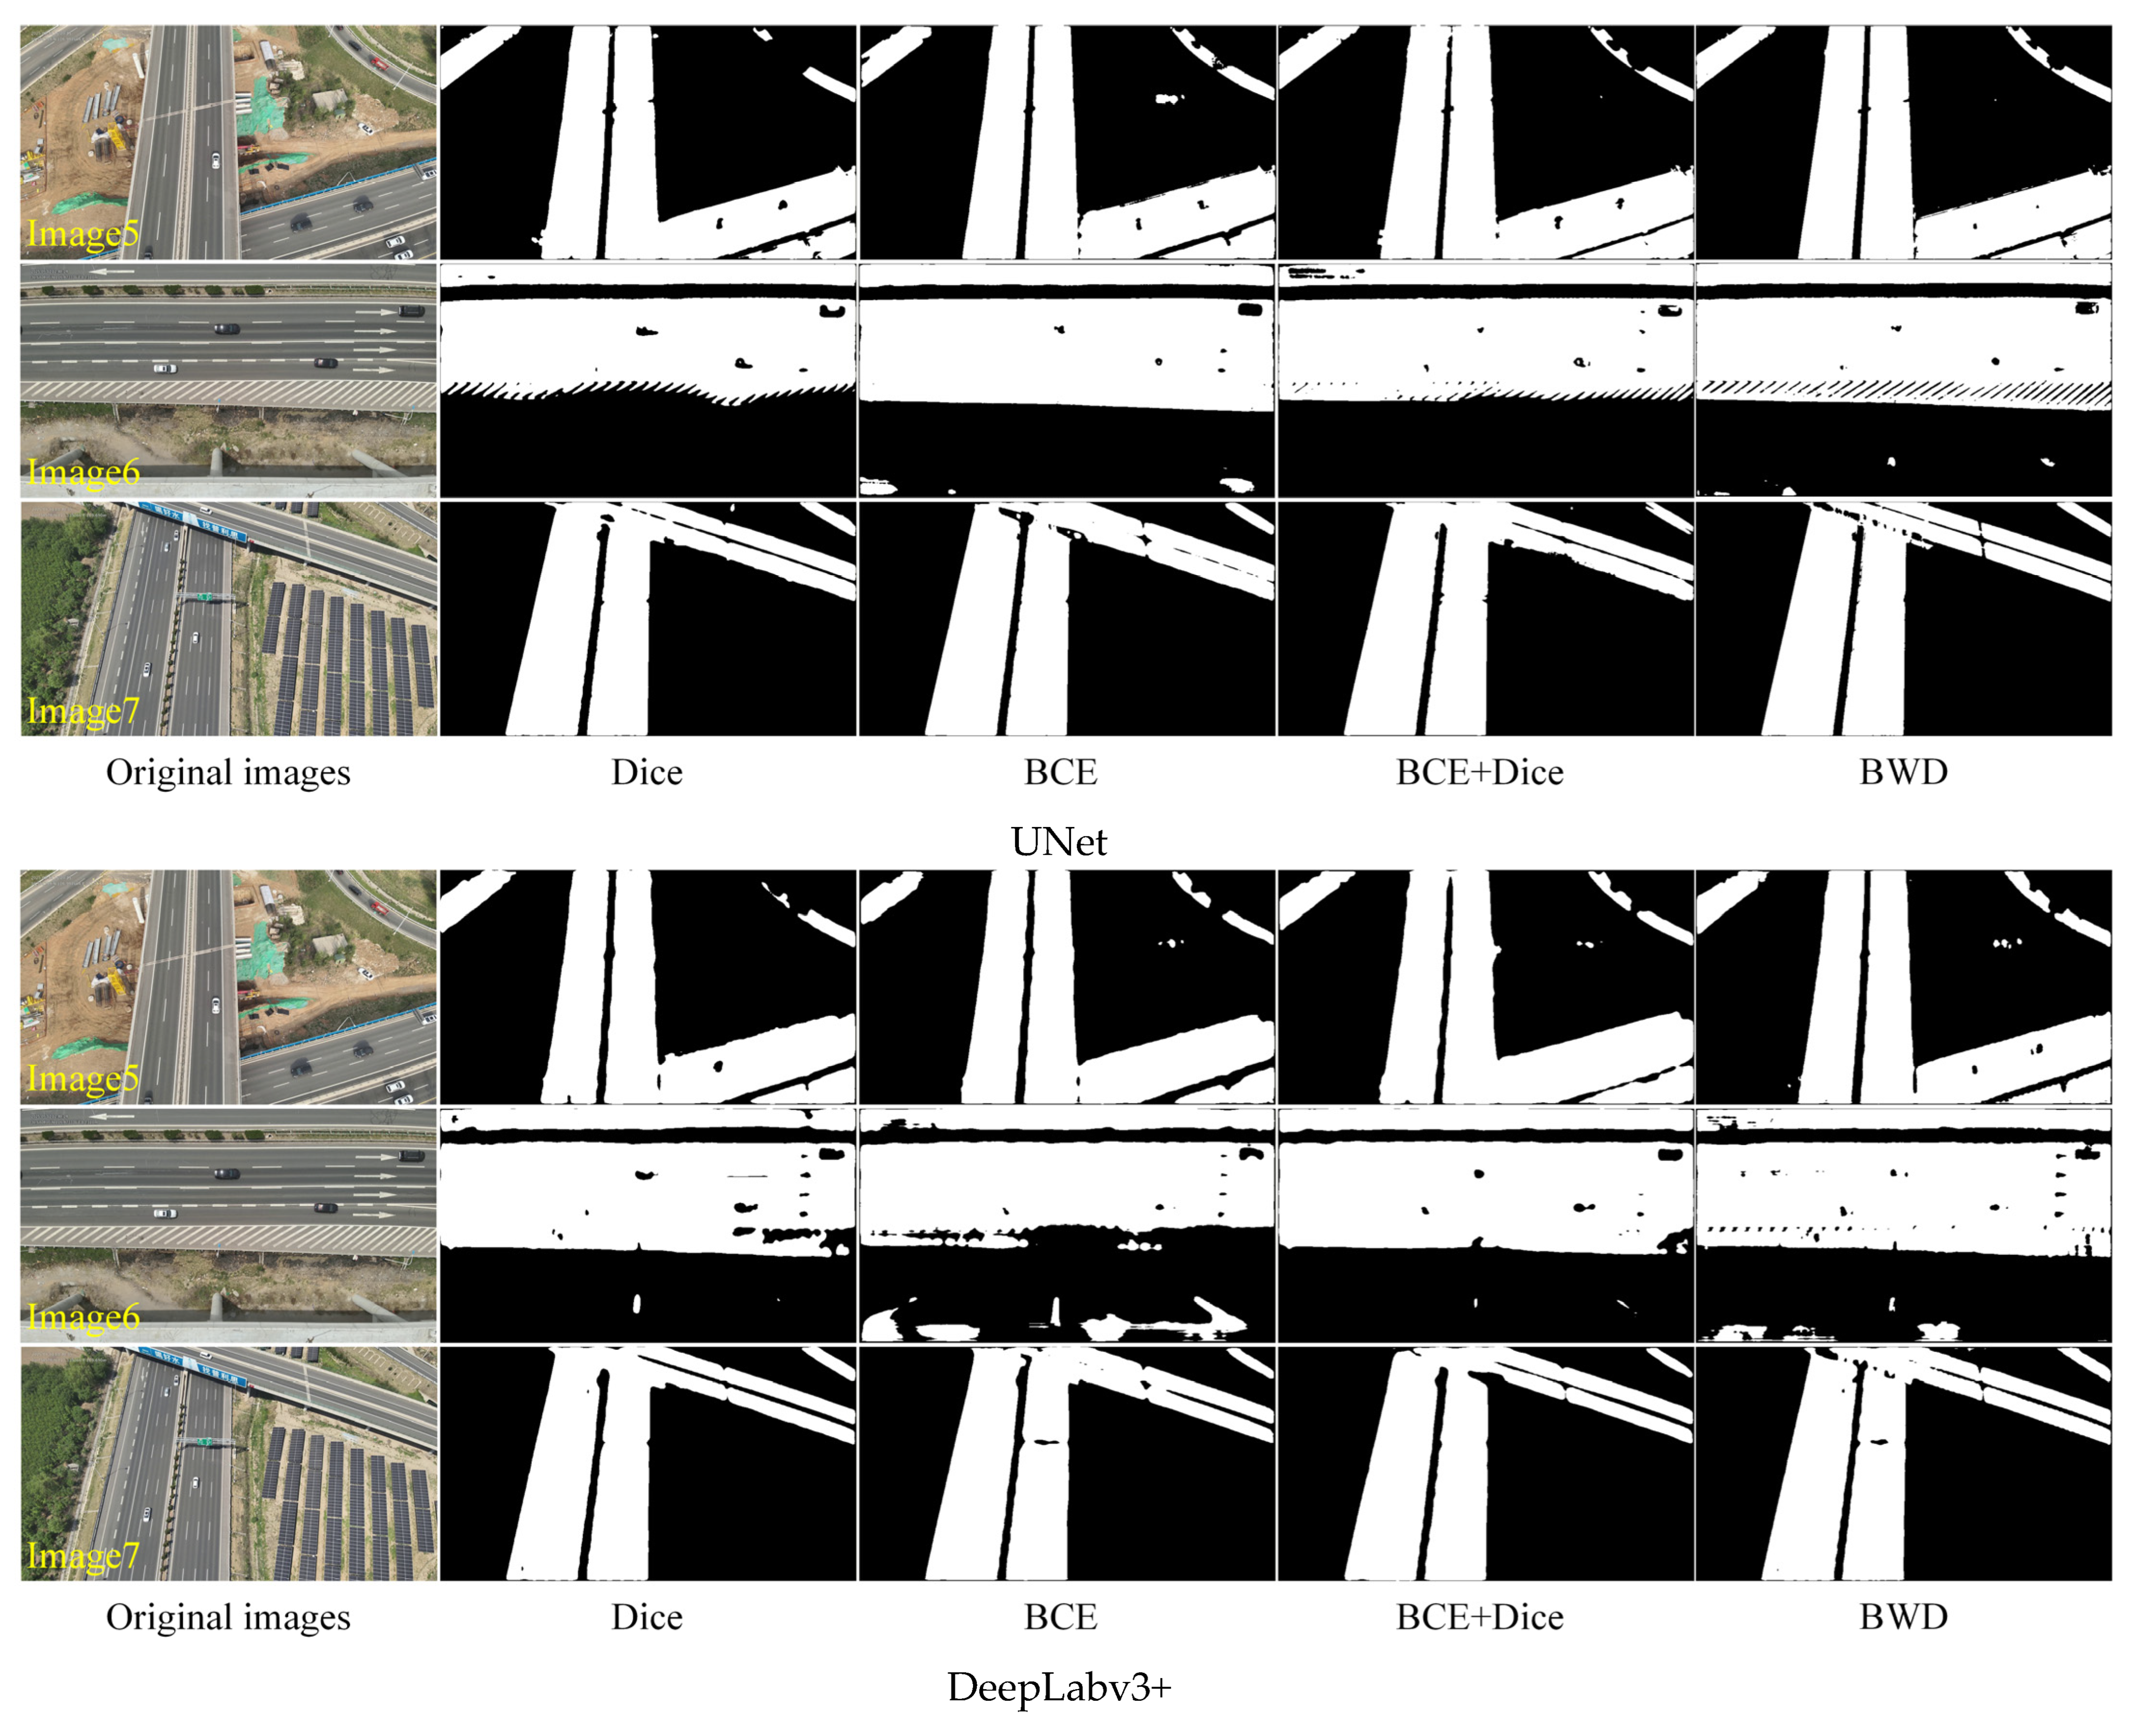
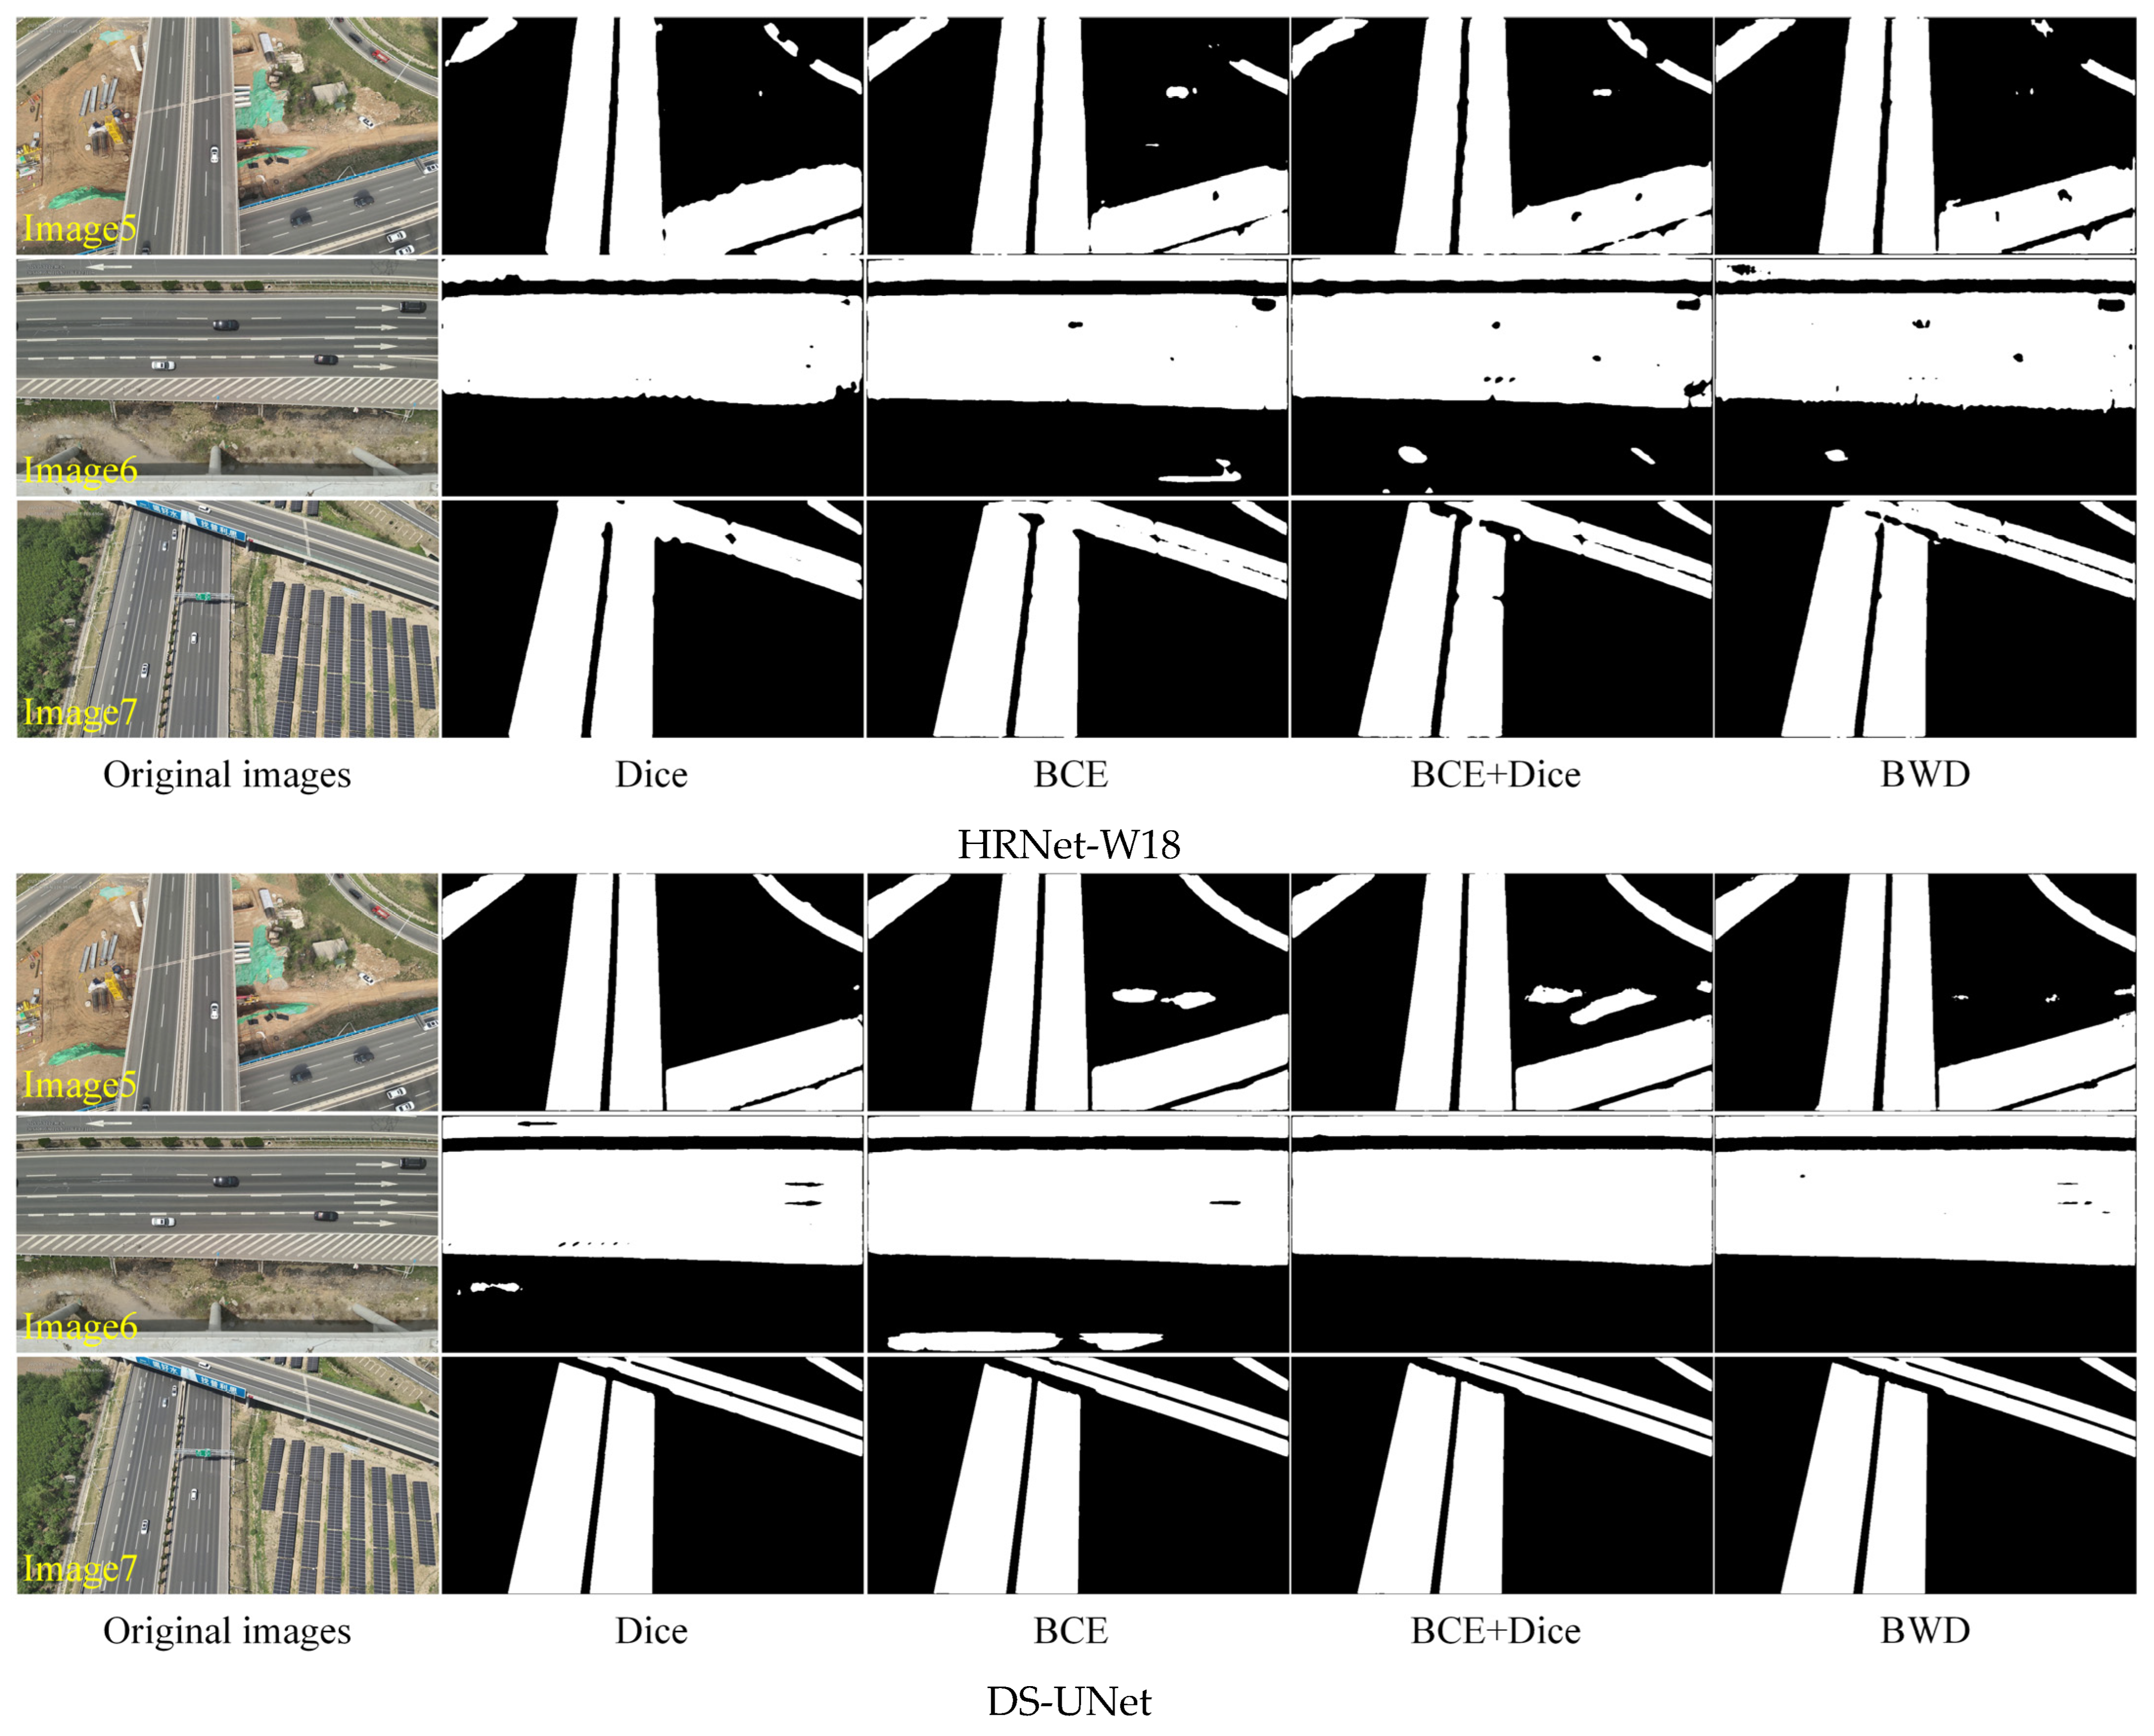
To further verify the effectiveness of the proposed boundary-weighted hybrid loss function for fine-grained road region segmentation, we select UNet, DeepLabv3+, HRNet-W18 and the proposed DS-UNet as experimental models. We train these models using Dice loss, BCE loss, Dice-BCE loss and our proposed BWD loss for subsequent performance comparison. In these experiments, λ1 and λ2 are both set to 1.0 to balance the relative contributions of the region-aware term and the boundary term during model training. Segmentation performance is evaluated in two dimensions: conventional region level metrics and boundary level metrics. Among these metrics, F1, Road-class IoU, Pr and Re are employed to quantify overall region-level segmentation performance, whereas BF1, BP and BR are utilized to evaluate road-boundary prediction quality. In our experiments, the boundary matching tolerance τ is set to 1, which permits a maximum offset of one pixel between predicted boundaries and ground-truth boundaries under the model’s input resolution. Since images are downsampled by a factor of two in both height and width during training and testing, this configuration yields an equivalent boundary-matching tolerance of approximately 2 pixels for the original 1920 × 1080 image scale. Quantitative results are reported in Table 4, while corresponding visual comparisons are provided in Figure 5.
Table 4.
Experimental results (%) for different semantic segmentation networks with different loss functions.
Figure 5.
Road region detection results for different loss functions.
As shown in Table 4, the proposed BWD achieves considerable improvements in BR across different network architectures. Given the practical requirements for fine-grained road region segmentation, boundary omissions frequently lead to incomplete road contours and region fragmentation. Improvement in boundary-recall helps preserve the integrity of road regions. Consequently, the gain in BR carries great practical significance for road-boundary recovery from the UAV aerial viewpoint. For our proposed DS-UNet, the BWD loss further boosts BR to 77.88%, representing the highest value across all loss function configurations. The results demonstrate that BWD assigns higher supervisory weights to road-boundary pixels during training, driving the model to place greater emphasis on ground-truth road-edge regions and strengthening its boundary-prediction completeness.
It should be noted that BWD cannot deliver the absolute best performance across every metric. For example, when BWD is integrated within our DS-UNet, F1 and Road-class IoU reach 97.17% and 94.50%, respectively, whereas BF1 and BP obtain 70.51% and 64.42%. These values show slight performance degradation compared with the results obtained with Dice or Dice-BCE loss. Similarly, a slight performance drop is also observed for DeepLabv3+ trained with BWD. This observation reveals that the effectiveness of the boundary-weighted hybrid loss varies across different network architectures, which may be influenced by multiple factors such as the inherent feature-modeling capability and context perception ability of the network. After additional boundary weight supervision is introduced, the model’s optimization focus shifts toward boundary recall to mitigate boundary-omission errors. Nevertheless, the enhanced boundary supervision may also cause the predicted boundary regions to dilate to a certain extent, leading to slight performance degradation of BP, BF1 and region-overlap metrics. The detailed internal mechanism behind the performance differences among different architectures remains to be further explored in follow-up research.
Figure 5 shows that different loss functions exert distinct effects on road-boundary prediction quality. When a single loss (Dice or BCE) is adopted, certain models tend to produce local missing road segments and inadequate contour alignment at road-edge regions. The Dice-BCE loss combination enhances the stability of overall region-level segmentation, especially for challenging scenarios with complex backgrounds. By contrast, BWD yields more complete road-edge contours in prediction outputs, especially for scenarios with blurred road boundaries. Nevertheless, as higher weights are assigned to boundary-region pixels during loss computation, the model tends to amplify learning signals around road-contour areas. For a few test samples, this may introduce local inconsistent predictions within road region interiors. Combining quantitative metrics and visualization results, it can be concluded that the proposed boundary-weighted hybrid loss further strengthens the model’s capability to recover ground-truth road boundaries, while largely preserving the overall segmentation performance of road regions. It therefore exerts positive effects on fine-grained road region segmentation from the UAV aerial viewpoint.
5. Conclusions and Future Work
This paper proposes DS-UNet, an improved UNet-based semantic segmentation framework for fine-grained highway region extraction from UAV perspective. To enhance feature representation of road region features against complex-background interference, a Dilated-Global Context Block (DGCBlock) is incorporated into the encoder. It jointly captures multi-scale local features and global contextual information via parallel dilated convolutions and global context modeling. Meanwhile, a Semantic-Guided Channel-Spatial Attention (SGCSA) module is incorporated into the decoder. It leverages high-level semantic features to guide channel and spatial feature calibration, thereby enhancing fine-detail reconstruction and suppressing irrelevant background feature responses. Furthermore, a boundary-weighted BCE-Dice hybrid loss (BWD) is devised to enhance supervisory weights for road-boundary pixels and boost boundary-prediction completeness. Experiments on the self-constructed UAVRR3K dataset verify the effectiveness of the proposed method. DS-UNet achieves an F1 of 97.31%, a Road-class IoU of 94.76%, a PA of 98.08%, a Re of 96.10%, and a Pr of 98.56%, outperforming other competing CNN- and Transformer-based segmentation models. In addition, the proposed boundary-weighted hybrid loss BWD further boosts boundary recall to 77.88%, which demonstrates its capability to mitigate boundary omissions. Overall, the improvements in road-region segmentation achieved by DGCBlock and SGCSA, together with the higher boundary recall obtained using BWD, indicate the potential of the proposed approach to support UAV-based highway inspection and traffic monitoring.
However, several limitations remain. First, the current experiments are primarily carried out on UAV imagery captured for highway scenarios under daytime illumination and relatively favorable weather conditions. Although the dataset covers different UAV perspectives, road structures, vehicle occlusions, shadows and roadside interference, the generalization performance of the proposed model under more challenging conditions—such as nighttime illumination, adverse weather, and large cross-region appearance variations—has not yet been sufficiently investigated. Rain, fog, low ambient illumination and strong glare tend to reduce the contrast between road surfaces and surrounding backgrounds, obscure fine-grained boundary details, and may consequently degrade segmentation accuracy. Second, the current BWD loss adopts a predefined boundary-weighting strategy. Experimental results show that emphasizing boundary pixels can effectively boost boundary recall. Nevertheless, excessively amplified boundary supervision signals may slightly degrade boundary precision, BF1 and region-overlap accuracy under certain conditions. Accordingly, a more favorable balance between regional segmentation and boundary refinement remains to be further explored.
Future work will focus on the following directions: (1) enriching the existing dataset with more diverse highway environments, including nighttime conditions, adverse-weather scenarios, distinct geographical regions, and greater variations in UAV flight altitude and viewing perspective, to further evaluate and improve the generalization performance of the proposed method; (2) investigating adaptive boundary supervision strategies whereby boundary weights are dynamically adjusted based on prediction uncertainty or local boundary geometric characteristics, so as to realize a more favorable trade-off between boundary completeness and accuracy; (3) further optimizing the network architecture with respect to model size and computational complexity, and exploring its deployment on UAV on-board edge-computing platforms for real-time highway region segmentation and intelligent road inspection.
Author Contributions
Conceptualization, Y.W. and H.L.; methodology, Y.W.; software, Y.W.; validation, Y.W., H.L. and L.Y.; formal analysis, Y.W. and H.L.; investigation, Y.W. and D.M.; resources, L.Y. and M.Z.; data curation, Y.W. and D.M.; writing—original draft preparation, Y.W.; writing—review and editing, Y.W., H.L. and L.Y.; visualization, Y.W. and M.Z.; supervision, Y.W. and H.L.; project administration, H.L., M.Z. and L.Y.; funding acquisition, H.L., M.Z. and L.Y. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by The National Natural Science Foundation of China under Grant 52672417, Shandong Natural Science Foundation Innovation and Development Joint Fund under Grant ZR2024LZN008 and Jinan City’s Self-Developed Innovative Team Project for Higher Educational Institutions under Grant 20233040.
Data Availability Statement
The original contributions presented in this study are included in the article. Further inquiries can be directed to the corresponding author.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| DGCBlock | Dilated Global Context block |
| SGCSA | Semantic-Guided Channel-Spatial Attention module |
References
- Li, B.; Gao, S.; Liang, Y.; Kang, Y.; Prestby, T.; Gao, Y.; Xiao, R. Estimation of Regional Economic Development Indicator from Transportation Network Analytics. Sci. Rep. 2020, 10, 2647. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Feng, D.; Haase-Schütz, C.; Rosenbaum, L.; Hertlein, H.; Gläser, C.; Timm, F.; Wiesbeck, W.; Dietmayer, K. Deep Multi-Modal Object Detection and Semantic Segmentation for Autonomous Driving: Datasets, Methods, and Challenges. IEEE Trans. Intell. Transp. Syst. 2021, 22, 1341–1360. [Google Scholar] [CrossRef] [Scilit]
- Butt, M.A.; Ali, H.; Qayyum, A.; Sultani, W.; Al-Fuqaha, A.; Qadir, J. R2S100K: Road-Region Segmentation Dataset for Semi-Supervised Autonomous Driving in the Wild. Int. J. Comput. Vis. 2025, 133, 910–928. [Google Scholar] [CrossRef] [Scilit]
- Radzi, S.F.M.; Abd Rahman, M.A.; Yusof, K.A.; Mohd Haniff, N.S.; Rahmat, R.F. Computationally Enhanced UAV-Based Real-Time Pothole Detection Using YOLOv7-C3ECA-DSA Algorithm. IEEE Access 2025, 13, 99092–99111. [Google Scholar] [CrossRef] [Scilit]
- Abbondati, F.; Biancardo, S.A.; Veropalumbo, R.; Dell’Acqua, G. Surface Monitoring of Road Pavements Using Mobile Crowdsensing Technology. Measurement 2021, 171, 108763. [Google Scholar] [CrossRef] [Scilit]
- Outay, F.; Mengash, H.A.; Adnan, M. Applications of Unmanned Aerial Vehicle (UAV) in Road Safety, Traffic and Highway Infrastructure Management: Recent Advances and Challenges. Transp. Res. Part A Policy Pract. 2020, 141, 116–129. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Zhu, J.; Zhong, J.; Ma, T.; Huang, X.; Zhang, W.; Zhou, Y. Pavement Distress Detection Using Convolutional Neural Networks with Images Captured via UAV. Autom. Constr. 2022, 133, 103991. [Google Scholar] [CrossRef] [Scilit]
- Astor, Y.; Nabesima, Y.; Utami, R.; Sihombing, A.V.R.; Adli, M.; Firdaus, M.R. Unmanned Aerial Vehicle Implementation for Pavement Condition Survey. Transp. Eng. 2023, 12, 100168. [Google Scholar] [CrossRef] [Scilit]
- Chen, Z.; Deng, L.; Luo, Y.; Li, D.; Marcato Junior, J.; Gonçalves, W.N.; Nurunnabi, A.A.M.; Li, J.; Wang, C.; Li, D. Road Extraction in Remote Sensing Data: A Survey. Int. J. Appl. Earth Obs. Geoinf. 2022, 112, 102833. [Google Scholar] [CrossRef] [Scilit]
- Jia, J.; Sun, H.; Jiang, C.; Karila, K.; Karjalainen, M.; Ahokas, E.; Khoramshahi, E.; Hu, P.; Chen, C.; Xue, T.; et al. Review on Active and Passive Remote Sensing Techniques for Road Extraction. Remote Sens. 2021, 13, 4235. [Google Scholar] [CrossRef] [Scilit]
- Chen, X.; Sun, Q.; Guo, W.; Qiu, C.; Yu, A. GA-Net: A Geometry Prior Assisted Neural Network for Road Extraction. Int. J. Appl. Earth Obs. Geoinf. 2022, 114, 103004. [Google Scholar] [CrossRef] [Scilit]
- Wang, Y.; Peng, Y.; Li, W.; Alexandropoulos, G.C.; Yu, J.; Ge, D.; Xiang, W. DDU-Net: Dual-Decoder-U-Net for Road Extraction Using High-Resolution Remote Sensing Images. IEEE Trans. Geosci. Remote Sens. 2022, 60, 4412612. [Google Scholar] [CrossRef] [Scilit]
- Jiang, X.; Li, Y.; Jiang, T.; Xie, J.; Wu, Y.; Cai, Q.; Jiang, J.; Xu, J.; Zhang, H. RoadFormer: Pyramidal Deformable Vision Transformers for Road Network Extraction with Remote Sensing Images. Int. J. Appl. Earth Obs. Geoinf. 2022, 113, 102987. [Google Scholar] [CrossRef] [Scilit]
- Du, Y.; Sheng, Q.; Zhang, W.; Zhu, C.; Li, J.; Wang, B. From Local Context-Aware to Non-Local: A Road Extraction Network via Guidance of Multi-Spectral Image. ISPRS J. Photogramm. Remote Sens. 2023, 203, 230–245. [Google Scholar] [CrossRef] [Scilit]
- Xu, H.; He, H.; Zhang, Y.; Ma, L.; Li, J. A Comparative Study of Loss Functions for Road Segmentation in Remotely Sensed Road Datasets. Int. J. Appl. Earth Obs. Geoinf. 2023, 116, 103159. [Google Scholar] [CrossRef] [Scilit]
- Abdollahi, A.; Pradhan, B.; Alamri, A. SC-RoadDeepNet: A New Shape and Connectivity-Preserving Road Extraction Deep Learning-Based Network from Remote Sensing Data. IEEE Trans. Geosci. Remote Sens. 2022, 60, 5617815. [Google Scholar] [CrossRef] [Scilit]
- Li, W.; Lan, T.; Fan, S.; Jiang, Y. RBFNet: A Region-Aware and Boundary-Enhanced Fusion Network for Road Extraction from High-Resolution Remote Sensing Data. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2024, 17, 16608–16624. [Google Scholar] [CrossRef] [Scilit]
- Lian, R.; Wang, W.; Mustafa, N.; Huang, L. Road Extraction Methods in High-Resolution Remote Sensing Images: A Comprehensive Review. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2020, 13, 5489–5507. [Google Scholar] [CrossRef] [Scilit]
- Li, L.; Wang, W.; Khatoon, A.; Wang, M. Road Detection by Using Gradient Magnitude Image and Adaptive Thresholding Based Watershed. Egypt. Inform. J. 2024, 25, 100446. [Google Scholar] [CrossRef] [Scilit]
- Dai, J.; Ma, R.; Ai, H. Semi-Automatic Extraction of Rural Roads from High-Resolution Remote Sensing Images Based on a Multifeature Combination. IEEE Geosci. Remote Sens. Lett. 2022, 19, 3000605. [Google Scholar] [CrossRef] [Scilit]
- Dai, J.; Zhu, T.; Wang, Y.; Ma, R.; Fang, X. Road Extraction from High-Resolution Satellite Images Based on Multiple Descriptors. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2020, 13, 227–240. [Google Scholar] [CrossRef] [Scilit]
- Lu, X.; Zhong, Y.; Zheng, Z.; Chen, D.; Su, Y.; Ma, A.; Zhang, L. Cascaded Multi-Task Road Extraction Network for Road Surface, Centerline, and Edge Extraction. IEEE Trans. Geosci. Remote Sens. 2022, 60, 5621414. [Google Scholar] [CrossRef] [Scilit]
- Soni, P.K.; Rajpal, N.; Mehta, R. Road Network Extraction Using Multi-Layered Filtering and Tensor Voting from Aerial Images. Egypt. J. Remote Sens. Space Sci. 2021, 24, 211–219. [Google Scholar] [CrossRef] [Scilit]
- Lian, R.; Zhang, Z.; Zou, C.; Huang, L. An Effective Road Centerline Extraction Method from VHR. IEEE Geosci. Remote Sens. Lett. 2022, 19, 6509205. [Google Scholar] [CrossRef] [Scilit]
- Miao, Z.; Shi, W.; Gamba, P.; Li, Z. An Object-Based Method for Road Network Extraction in VHR Satellite Images. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2015, 8, 4853–4862. [Google Scholar] [CrossRef] [Scilit]
- Maboudi, M.; Amini, J.; Malihi, S.; Hahn, M. Integrating Fuzzy Object Based Image Analysis and Ant Colony Optimization for Road Extraction from Remotely Sensed Images. ISPRS J. Photogramm. Remote Sens. 2018, 138, 151–163. [Google Scholar] [CrossRef] [Scilit]
- Wu, Y.; Zhao, Q.; Li, Y. Top-to-Down Segment Process Based Urban Road Extraction from High-Resolution Remote Sensing Image. Egypt. J. Remote Sens. Space Sci. 2022, 25, 851–861. [Google Scholar] [CrossRef] [Scilit]
- Wu, Y.; Wang, C. Integrated Point-Line-Network Model for Road Extraction Based on Tree-Shaped Point Process. Egypt. J. Remote Sens. Space Sci. 2025, 28, 348–356. [Google Scholar] [CrossRef] [Scilit]
- Long, J.; Shelhamer, E.; Darrell, T. Fully Convolutional Networks for Semantic Segmentation. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 7–12 June 2015; pp. 3431–3440. [Google Scholar] [CrossRef] [Scilit]
- Badrinarayanan, V.; Kendall, A.; Cipolla, R. SegNet: A Deep Convolutional Encoder-Decoder Architecture for Image Segmentation. IEEE Trans. Pattern Anal. Mach. Intell. 2017, 39, 2481–2495. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Ronneberger, O.; Fischer, P.; Brox, T. U-Net: Convolutional Networks for Biomedical Image Segmentation. In Medical Image Computing and Computer-Assisted Intervention—MICCAI 2015; Springer: Cham, Switzerland, 2015; Volume 9351, pp. 234–241. [Google Scholar] [CrossRef] [Scilit]
- Chen, Z.; Wang, C.; Li, J.; Fan, W.; Du, J.; Zhong, B. Adaboost-Like End-to-End Multiple Lightweight U-Nets for Road Extraction from Optical Remote Sensing Images. Int. J. Appl. Earth Obs. Geoinf. 2021, 100, 102341. [Google Scholar] [CrossRef] [Scilit]
- Yang, M.; Yuan, Y.; Liu, G. SDUNet: Road Extraction via Spatial Enhanced and Densely Connected UNet. Pattern Recognit. 2022, 126, 108549. [Google Scholar] [CrossRef] [Scilit]
- Wu, Q.; Luo, F.; Wu, P.; Wang, B.; Yang, H.; Wu, Y. Automatic Road Extraction from High-Resolution Remote Sensing Images Using a Method Based on Densely Connected Spatial Feature-Enhanced Pyramid. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2021, 14, 3–17. [Google Scholar] [CrossRef] [Scilit]
- Liu, Z.; Wu, W.; Wang, D.; Cui, B.; Gu, X. Automatic Extraction and 3D Modeling of Real Road Scenes Using UAV Imagery and Deep Learning Semantic Segmentation. Int. J. Digit. Earth 2024, 17, 2365970. [Google Scholar] [CrossRef] [Scilit]
- Zhou, M.; Sui, H.; Chen, S.; Liu, J.; Shi, W.; Chen, X. Large-Scale Road Extraction from High-Resolution Remote Sensing Images Based on a Weakly-Supervised Structural and Orientational Consistency Constraint Network. ISPRS J. Photogramm. Remote Sens. 2022, 193, 234–251. [Google Scholar] [CrossRef] [Scilit]
- Chen, H.; Yang, L.; Jia, Q.; Xiong, W. RoadFocusNet: Road Extraction from Remote Sensing Imagery Using Focused Transformer and Focused Masked Image Modeling. Int. J. Digit. Earth 2025, 18, 2549435. [Google Scholar] [CrossRef] [Scilit]
- Li, R.; Gao, B.; Xu, Q. Gated Auxiliary Edge Detection Task for Road Extraction with Weight-Balanced Loss. IEEE Geosci. Remote Sens. Lett. 2021, 18, 786–790. [Google Scholar] [CrossRef] [Scilit]
- Shit, S.; Paetzold, J.C.; Sekuboyina, A.; Ezhov, I.; Unger, A.; Zhylka, A.; Pluim, J.P.W.; Bauer, U.; Menze, B.H. clDice—A Novel Topology-Preserving Loss Function for Tubular Structure Segmentation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 20–25 June 2021; pp. 16555–16564. [Google Scholar] [CrossRef] [Scilit]
- Nanni, L.; Brahnam, S.; Loreggia, A. An Enhanced Loss Function for Semantic Road Segmentation in Remote Sensing Images. IEEE Access 2024, 12, 74218–74229. [Google Scholar] [CrossRef] [Scilit]
- Shojaei, S.; Bohl, T.; Palaniappan, K.; Bunyak, F. Adaptive Structure-Aware Connectivity-Preserving Loss for Improved Road Segmentation in Remote Sensing Images. In Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision Workshops (WACVW), 28 February–4 March 2025; pp. 1120–1128. [Google Scholar] [CrossRef] [Scilit]
- Fu, J.; Wang, C.; Liu, M.; Li, X.; Liu, Y.; Shi, W.; Wang, R. HyperR3SNet: Leveraging Hyperbolic Space and Vision Foundation Models for Remote Sensing Semantic Segmentation. IEEE Trans. Geosci. Remote Sens. 2026, 64, 5620016. [Google Scholar] [CrossRef] [Scilit]
- Wang, B.; Lv, S.; Li, Z.; Deng, F.; Liu, Y. MsRE: Towards Efficient Remote Sensing Segmentation via Vision Foundation Models. IEEE Trans. Geosci. Remote Sens. 2026, 64, 5631115. [Google Scholar] [CrossRef] [Scilit]
- Zhou, Z.; Rahman Siddiquee, M.M.; Tajbakhsh, N.; Liang, J. UNet++: A Nested U-Net Architecture for Medical Image Segmentation. In Deep Learning in Medical Image Analysis and Multimodal Learning for Clinical Decision Support; Springer: Cham, Switzerland, 2018; Volume 11045, pp. 3–11. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Chen, L.-C.; Zhu, Y.; Papandreou, G.; Schroff, F.; Adam, H. Encoder-Decoder with Atrous Separable Convolution for Semantic Image Segmentation. In Computer Vision—ECCV 2018; Springer: Cham, Switzerland, 2018; Volume 11211, pp. 833–851. [Google Scholar] [CrossRef] [Scilit]
- Guo, C.; Szemenyei, M.; Yi, Y.; Wang, W.; Chen, B.; Fan, C. SA-UNet: Spatial Attention U-Net for Retinal Vessel Segmentation. In Proceedings of the 25th International Conference on Pattern Recognition (ICPR), Milan, Italy, 10–15 January 2021; pp. 1236–1242. [Google Scholar] [CrossRef] [Scilit]
- Wang, J.; Sun, K.; Cheng, T.; Jiang, B.; Deng, C.; Zhao, Y.; Liu, D.; Mu, Y.; Tan, M.; Wang, X.; et al. Deep High-Resolution Representation Learning for Visual Recognition. IEEE Trans. Pattern Anal. Mach. Intell. 2021, 43, 3349–3364. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Xie, E.; Wang, W.; Yu, Z.; Anandkumar, A.; Alvarez, J.M.; Luo, P. SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers. In NIPS’21: 35th International Conference on Neural Information Processing Systems; Curran Associates Inc.: Red Hook, NY, USA, 2021; Volume 34, pp. 12077–12090. [Google Scholar]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.