


Highlights
What are the main findings?
- Developed MAIENet, a single-backbone multimodal SAR object detection framework built upon YOLOv11m, integrating three dedicated modules: BSCC (batch-wise splitting and channel-wise concatenation), MAIE (modality-aware adaptive interaction enhancement), and MF (multi-directional focus). These modules jointly exploit complementary SAR-optical features, delivering mAP50 on the OGSOD-1.0 dataset.
- Compared with leading multimodal benchmarks such as DEYOLO and CoLD, MAIENet achieves superior detection accuracy while retaining fewer parameters than dual-backbone designs, despite necessarily introducing additional parameters relative to the YOLOv11m baseline.
What is the implication of the main finding?
- Demonstrates that carefully designed single-backbone multimodal fusion can outperform both unimodal and dual-backbone multimodal detectors, achieving a better balance between accuracy gains and parameter increments.
- Validates the efficacy of BSCC, MAIE, and MF modules in enhancing cross-modal feature interaction and receptive field coverage, showing their potential for improving detection of diverse target scales (bridges, harbors, oil tanks) in complex SAR-optical remote sensing scenarios.
Abstract
Syntheticaperture radar (SAR) object detection offers significant advantages in remote sensing applications, particularly under adverse weather conditions or low-light environments. However, single-modal SAR image object detection encounters numerous challenges, including speckle noise, limited texture information, and interference from complex backgrounds. To address these issues, we present Modality-Aware Adaptive Interaction Enhancement Network (MAIENet), a multimodal detection framework designed to effectively extract complementary information from both SAR and optical images, thereby enhancing object detection performance. MAIENet comprises three primary components: batch-wise splitting and channel-wise concatenation (BSCC) module, modality-aware adaptive interaction enhancement (MAIE) module, and multi-directional focus (MF) module. The BSCC module extracts and reorganizes features from each modality to preserve their distinct characteristics. The MAIE module component facilitates deeper cross-modal fusion through channel reweighting, deformable convolutions, atrous convolution, and attention mechanisms, enabling the network to emphasize critical modal information while reducing interference. By integrating features from various spatial directions, the MF module expands the receptive field, allowing the model to adapt more effectively to complex scenes. The MAIENet framework is end-to-end trainable and can be seamlessly integrated into existing detection networks with minimal modifications. Experimental results on the publicly available OGSOD-1.0 dataset demonstrate that MAIENet achieves superior performance compared with existing methods, achieving 90.8% .
1. Introduction
Synthetic aperture radar (SAR) imaging offers key advantages in maritime surveillance [1] and land reconnaissance [2] through its capability to operate under all-weather conditions and independently of sunlight, enabling day-and-night observations. By actively transmitting and receiving microwave signals, SAR can penetrate cloud cover, haze, and other atmospheric obstructions that typically hinder optical sensors. This insensitivity to illumination also allows effective imaging during periods of low natural light, such as at night or in high-latitude regions where daylight is limited. Nevertheless, SAR object detection continues to face challenges from complex background clutter, which can degrade accuracy.
Traditional SAR detection methods, such as SnP-CFAR [3] and saliency-driven approaches [4], rely on handcrafted features with limited robustness in complex environments. With the rise of deep learning, YOLO-based single-stage detectors [5,6,7,8,9,10,11,12] have been widely adopted in SAR tasks due to their speed and scalability. Lightweight YOLO variants, such as CSD-YOLO [13] and MAEE-Net [14], enhance multi-scale feature fusion and attention modeling to improve object detection in complex maritime scenes, while DFES-Net [15] integrates depthwise separable deformable convolutions and a receptive field enhancement module to adapt convolutional sampling positions to ship shapes and improve the detection of nearshore and densely packed small targets. Despite these advances, existing single-stage detectors still face accuracy challenges in cluttered maritime or land scenes and remain constrained by single-modality SAR inputs.
Although deep learning methods have alleviated many of the shortcomings of traditional SAR object detection—particularly in handling complex backgrounds—persistent issues remain. These include edge blurring due to speckle noise and weak object responses caused by limited texture information. Recent advancements in satellite imaging have enabled the use of optical imagery, which provides richer spatial and texture details, to complement SAR data. Fusing SAR and optical modalities in a multimodal detection framework can mitigate single-modality limitations and significantly enhance performance [16,17,18,19,20]. Cross-modal knowledge distillation (KD) has emerged as an effective technique to transfer semantic and localization cues from optical to SAR data [16,17,18,19], with notable works such as CoLD [19] built upon YOLOv5. While CoLD improves SAR-only detection via optical-guided teacher–student training, its interaction remains uni-directional and is limited to the training process, making it unsuitable for fully exploiting multimodal input during inference. Moreover, KD methods often incur high computational costs and dependency on pre-trained teacher models, restricting deployment. Recent research [21,22,23,24] has proposed new approaches that utilize multi-branch feature fusion to enhance interaction between multimodal data and improve detection performance. However, these methods often employ dual-stream feature extraction networks for cross-modal integration, which inevitably introduce greater computational overhead.
In order to overcome the limitations of single-modal SAR object detection and leverage the complementary advantages of optical images to achieve more robust SAR object detection, we propose MAIENet, a modal-aware interaction enhancement network, to improve SAR object detection performance by enhancing the interaction between optical and SAR images. First, batch-wise splitting and channel-wise concatenation (BSCC) module efficiently separates SAR and optical features while integrating them in a channel-consistent manner, preserving unique modal characteristics for unified processing. Second, the modal-aware adaptive interaction enhancement (MAIE) module facilitates adaptive cross-modal fusion through techniques such as channel reweighting, deformable convolution, atrous convolution, and attention mechanisms, enabling the network to focus on critical semantic and texture information. Third, the multi-direction focus (MF) module enhances the receptive field by aggregating spatial information in horizontal, vertical, and diagonal directions, thereby improving detection performance in complex scenes. Unlike conventional KD strategies that rely on pre-trained teacher models and require a lot of computational costs, the single-stream MAIENet is end-to-end trainable, lightweight, and modular, offering broad applicability. In summary, our contributions include the following:
- (1)
- We propose a multimodal SAR object detection framework that exploits complementary information from SAR and optical images to boost detection accuracy.
- (2)
- The proposed BSCC module first separates modal-specific features, and then performs channel fusion, which facilitates subsequent unified processing while retaining the features of different modes.
- (3)
- We introduce the MAIE module to integrate channel reweighting, deformable convolution, atrous convolution, and attention mechanism to achieve deeper cross-modal dual interaction and strengthen feature representation.
- (4)
- We propose a MF module to expand the receptive field by aggregating multi-directional spatial contexts, improving robustness in complex environments.
- (5)
- Comprehensive experiments on the public OGSOD-1.0 dataset show that MAIENet outperforms existing methods and effectively utilizes multimodal information to improve object detection performance in challenging scenarios.
2. Related Work
Early SAR object detection methods relied on handcrafted features such as Snp-CFAR [3] and enhanced directional smoothing (EDS) [4], which aimed to address scattering variability and speckle noise suppression. However, these methods lack robustness in complex scenes and show poor generalization.
With the emergence of deep learning, YOLO-based single-stage detectors have become widely used in SAR detection for their speed and end-to-end efficiency. MIS-YOLOv8 [8] enhances feature extraction via a multi-stage module and depthwise convolutions, while SCL-YOLOv11 [25] employs lightweight modules such as StarNet and C3k2-Star to improve efficiency. DFES-Net [15] further explores lightweight and shape-adaptive feature extraction for SAR ship detection by integrating depthwise separable deformable convolution (DWDCN) into the backbone and introducing a receptive field enhancement module based on dilated convolutions to improve the detection of nearshore and densely packed small targets. In addition, DFES-Net designs a CADIoU regression loss to refine bounding box localization and adopts a magnitude-based dynamic hierarchical pruning strategy to reduce parameters and accelerate inference, achieving a compact model while maintaining high accuracy. Anchor-free designs such as ATSS [26] and ObjectBox [27] also improve robustness without predefined anchors. Two-stage detectors (e.g., RepPoints [28], Sparse R-CNN [29]) and Transformer-based models such as SARATR-X [30], CoDeSAR [31], and RT-DETR [32] can further enhance object localization and global context modeling, but typically incur higher computational cost and are less suitable for lightweight or real-time SAR applications. Overall, these single- and two-stage SAR detectors demonstrate the effectiveness of task-specific architectural modifications and model compression, but they still operate on single-modality SAR data and do not exploit complementary optical information.
To overcome single-modality limitations, multimodal fusion methods integrate optical and SAR data. Shared-specific feature learning and domain adaptation have been proposed to align heterogeneous feature spaces and improve interaction, but strict feature alignment is difficult due to imaging mechanism differences. These methods often require paired SAR-optical images even at inference stage, limiting practicality.
Cross-modal knowledge distillation (KD) is a popular approach to transfer semantic cues from optical to SAR data. Bae et al. [33] presented a dense flow-based KD with stepwise transfer; Dai et al. [34] proposed GID, which selects informative instances based on teacher–student classification score gaps and performs feature-, response-, and relation-level distillation; Zhao et al. [35] introduced DKD, decoupling KD loss into target-class (TCKD) and non-target-class (NCKD) components; Zheng et al. [36] developed localization distillation (LD), separating semantic and positional knowledge for transfer; Wang et al. proposed CoLD [19], using an optical-based teacher with a candidate partitioning module (CPM) and IoU-based weighting module (IWM) to focus SAR detection on high-quality knowledge during training. While KD approaches are effective, challenges remain: high-dimensional teacher features can lose fine-grained detail when compressed; most frameworks lack sufficient bidirectional interaction between modalities; conventional KD losses underperform in dense or ambiguous boundary scenes.
Dual-stream backbone methods, such as DEYOLO [21], CMADet [23], CSSA [24], and ICAFusion [22], aim to tackle these challenges by employing parallel feature extraction and cross-branch enhancement mechanisms to reinforce inter-modal complementarity and feature interaction. However, such architectures typically incur significantly higher computational and memory costs, which limits their suitability for lightweight detection tasks. In contrast to the above dual-stream architectures and KD-based optical-SAR distillation methods (e.g., CoLD [19]), our MAIENet adopts a single-stream, YOLO-style detection framework that treats SAR and optical images within a unified backbone. By introducing the BSCC module to decouple and then fuse modality-specific channels, and the MAIE and MF modules to perform adaptive cross-modal interaction and multi-directional context aggregation, MAIENet enhances multimodal feature representation without relying on heavy dual-backbone designs or teacher–student training. This design is more suitable for lightweight deployment while still effectively exploiting the complementary characteristics of SAR and optical modalities.
3. Method
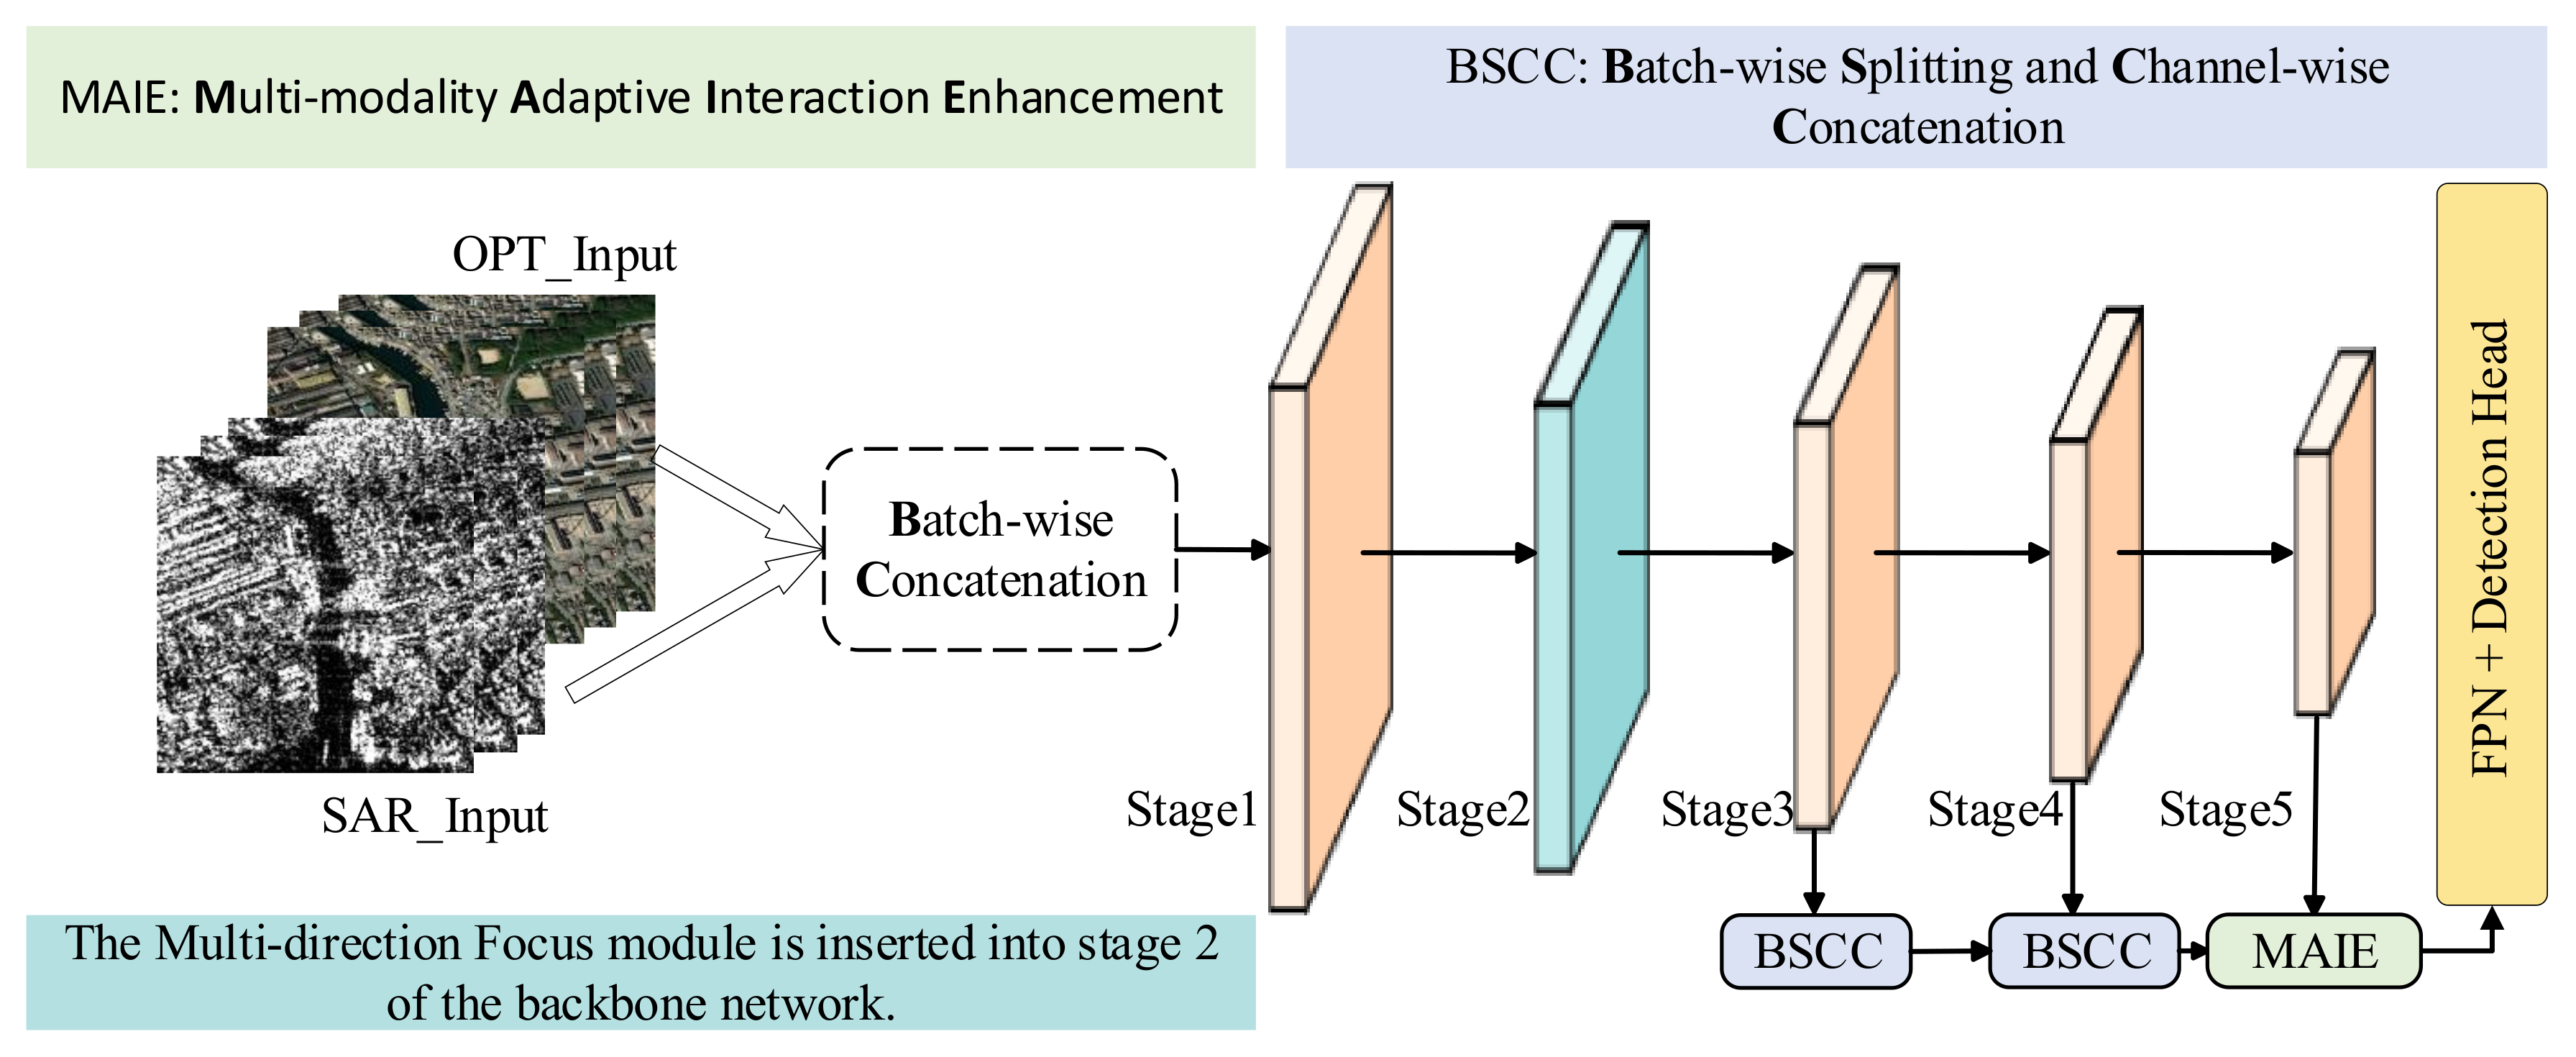
To exploit the complementary characteristics of multimodal remote sensing data, such as SAR and optical imagery, we propose a unified and modular feature enhancement framework, termed MAIENet (Figure 1). The framework follows three design principles: (i) modality-aware decomposition to avoid premature feature mixing, (ii) adaptive bidirectional cross-modal interaction to fully exploit complementary cues, and (iii) robust yet lightweight feature fusion to retain high accuracy under edge-device constraints. It comprises three core components: the BSCC module for modality separation and initial fusion, the MAIE module for multiscale weighting and cross-modal refinement, and the MF module for directional context aggregation and receptive field expansion.
Figure 1.
Overall architecture of the proposed MAIENet.
Given a backbone feature map , where the batch dimension holds paired SAR and optical inputs, the BSCC module separates and concatenates modality-specific features into a unified embedding. The MAIE module then enhances representations via channel reweighting, deformable pyramid convolutions, and attention-guided interactions, enabling deeper cross-modal integration. Finally, the MF module aggregates directional context from four orientations (horizontal, vertical, and diagonals) to enrich both local and global representations. It is noteworthy that, in the YOLOv11 backbone configuration used here, we have removed the original Pyramid Squeeze Attention (PSA) module. As confirmed in subsequent experiments, this change slightly improves detection accuracy while further reducing model size and FLOPs. The overall architecture is end-to-end trainable and compatible with different vision backbones and tasks. The following subsections describe each component in detail.
3.1. BSCC Module
The BSCC module is designed as an intermediate fusion plugin that preprocesses backbone features to be modality-aware, while avoiding the heavy parameter overhead of dual-branch fusion architectures [21,22,23]. Unlike input-level fusion, which mixes heterogeneous signals prematurely and risks feature confusion, BSCC operates at intermediate backbone stages (e.g., after Stage 3 and Stage 4 in our YOLO-style implementation), where both sufficient spatial detail and semantic abstraction are available. This choice maximizes complementarity while preserving computational efficiency.
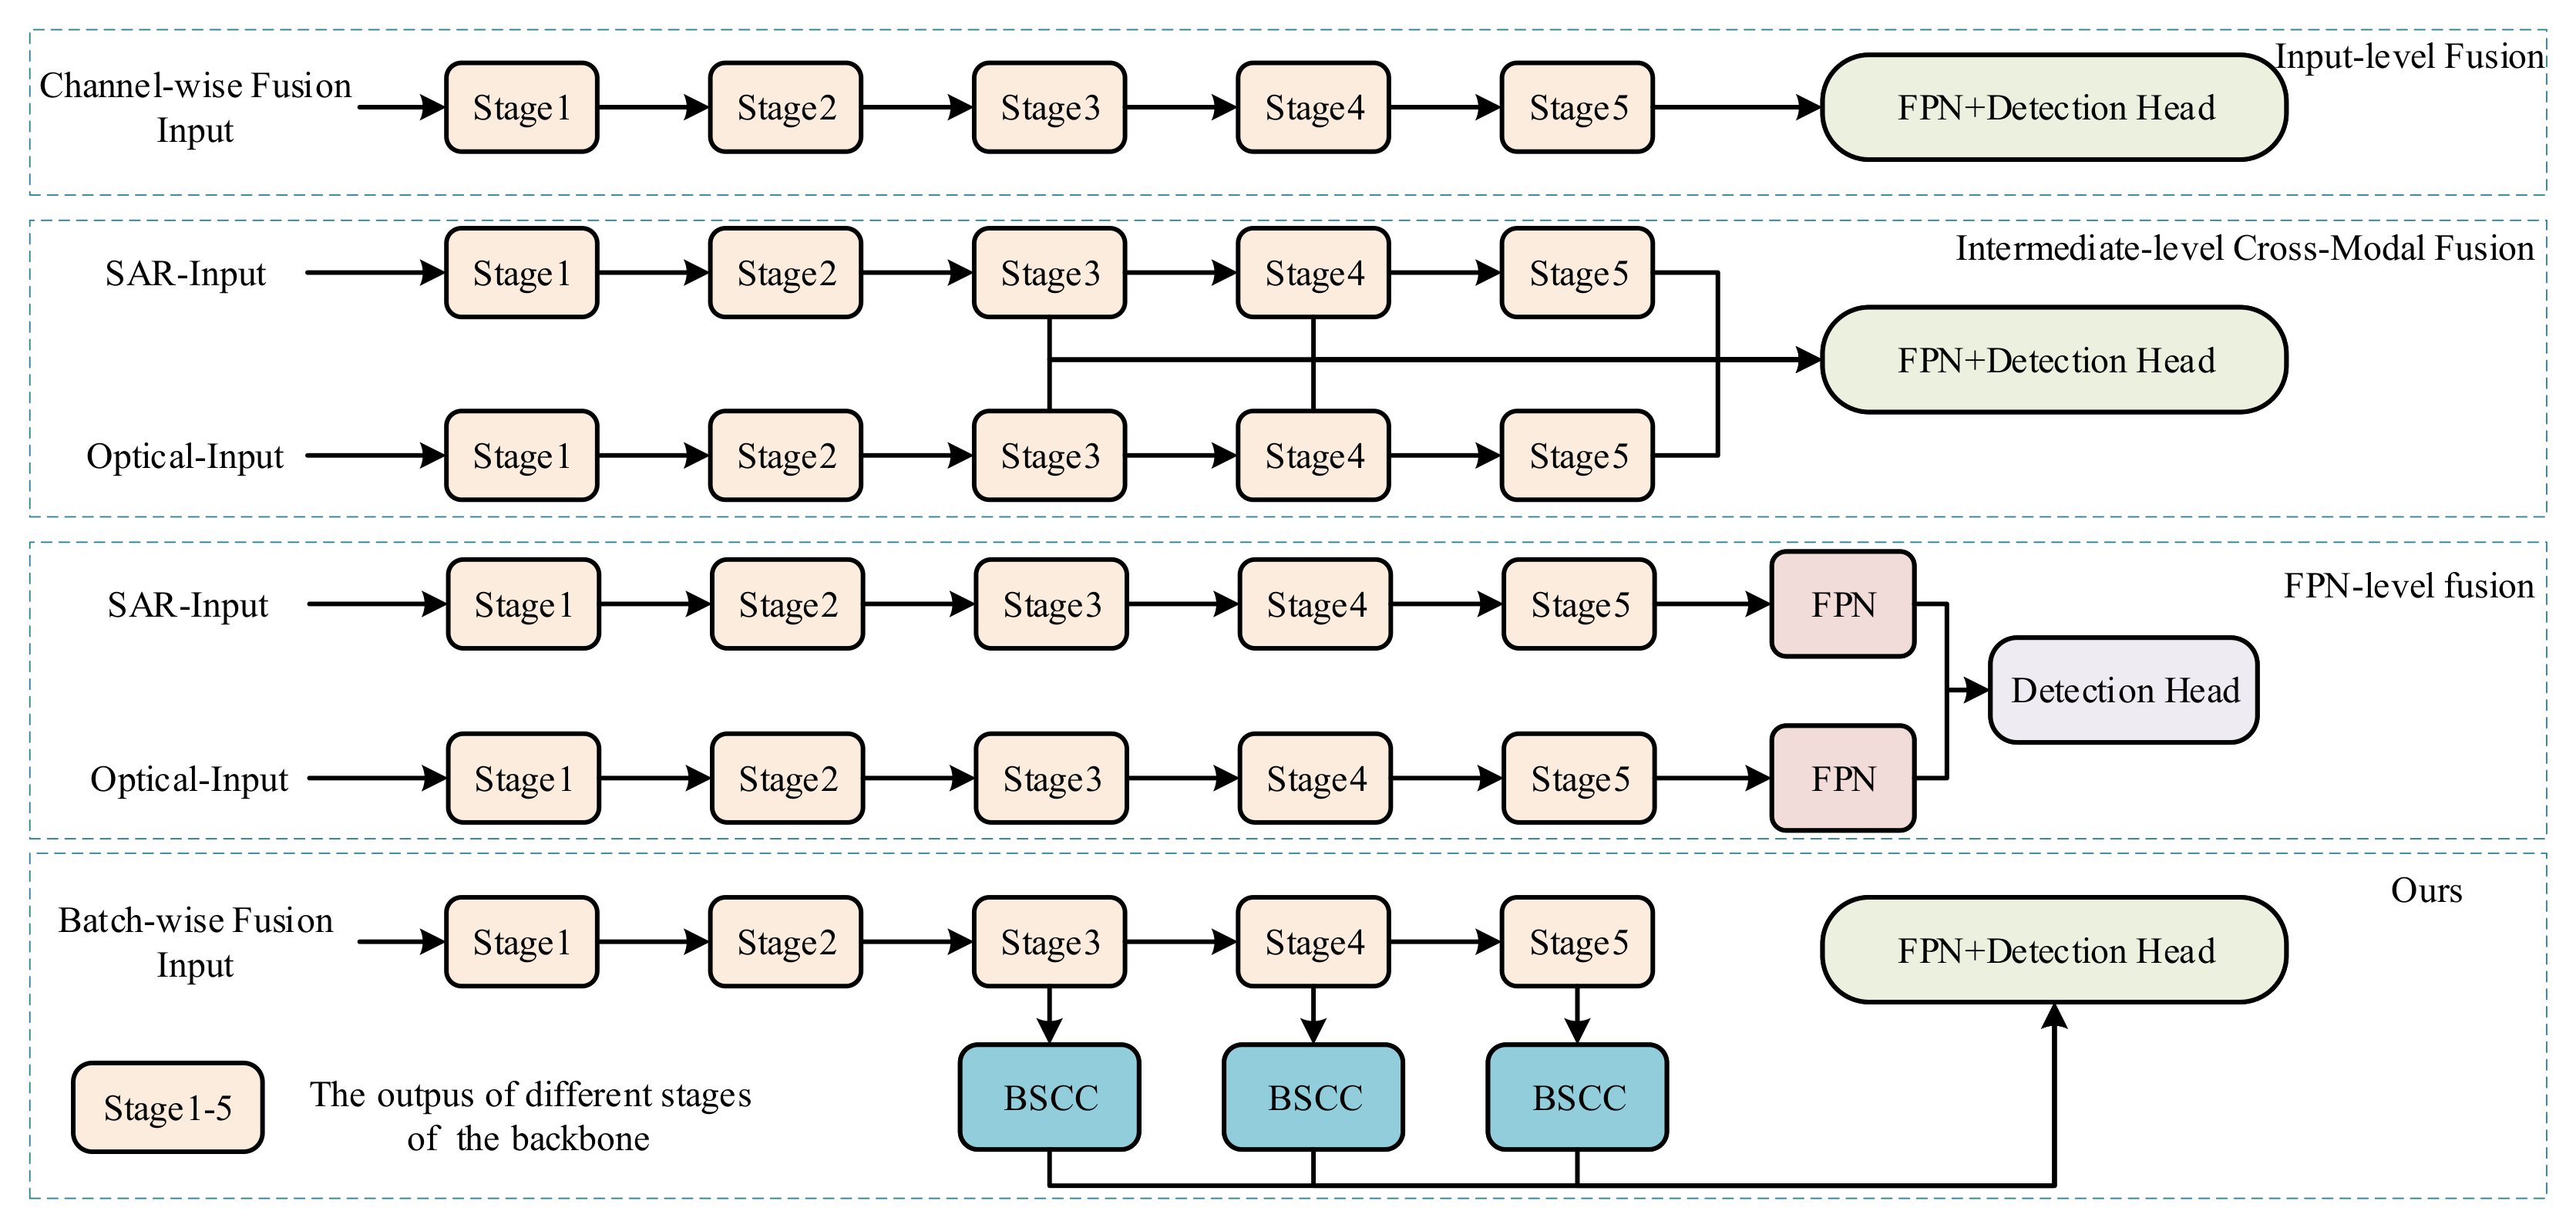
As shown in Figure 2, the module takes paired SAR-optical features from the backbone and merges them along the channel dimension. Let the backbone output be
where the batch dimension contains b SAR samples and b optical samples in matched order. BSCC first splits the batch along the batch axis into modality-specific tensors:
and then concatenates them along the channel axis to form a unified embedding:
Figure 2.
Multimodal frameworks for SAR images and optical images. Input-level fusion prematurely fuses multimodal data, resulting in feature confusion between modes, which is not conducive to feature extraction. Although the multimodal fusion strategy of intermediate-level cross-modal fusion and FPN-level fusion effectively utilizes the multimodal characteristics, the dual-branch architecture still introduces additional parameters.
To handle batches where either SAR or optical samples are missing (e.g., unpaired inference data), the SplitBatch operation uses index mapping and zero-filling so the output shapes remain aligned. This preserves GPU memory layout and parallelism, ensuring no stride mismatch with subsequent convolutions. Data loaders enforce modal pairing at input time to prevent misalignment.
By operating as an in-place stage plugin, BSCC integrates seamlessly into various backbones: if resolution or channel counts differ across stages, lightweight bottleneck convolutions are used to adapt feature shapes before or after BSCC. These integration details improve reproducibility and stability during training while keeping latency and memory overhead minimal.
3.2. MAIE Module
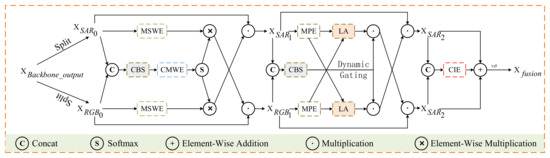
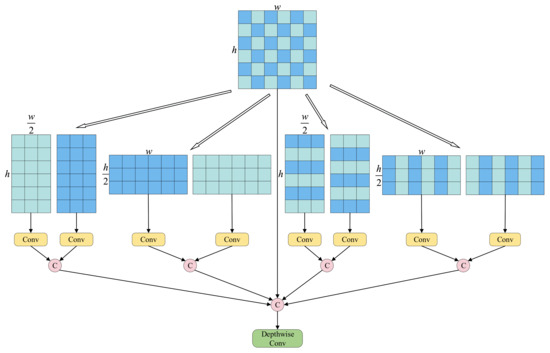
The MAIE module is an advanced multimodal interaction unit designed to adaptively integrate SAR and optical features through coordinated channel reweighting, multi-scale deformable convolutions, atrous spatial aggregation, and dual-path attention mechanisms (Figure 3). It is integrated at the deep semantic stage of the backbone (after Stage 5 in our YOLO-based experiments). This placement maximizes semantic richness while preserving sufficient spatial resolution for receptive field expansion.
Figure 3.
Architecture diagram of MAIE module.
For the feature map of the backbone , we split it along the batch dimension into SAR feature map and optical feature map , the modal-specific weight and are calculated as:
where refers to the modal-specific weight extraction (MSWE) operation as follows:
where is the adaptive average pooling operation, and are fully-connected layers, is the rectified linear unit activation function, and is the sigmoid function.
For the mixed feature map , the cross-modality weight is obtained:
where refers to the cross-modality weight extraction operation:
where is the sigmoid-weighted linear unit, is the two-dimensional batch normalization, is a convolutional layer, and refers to the proposed dynamic deformable convolution pyramid (DDCP) module:
where i refers to pyramid level, is a learnable parameter to ensure non-degenerate weighting, is weight, and is a dynamic deformable convolution(DDConv) layer with kernel , N denotes the number of effective pyramid branches which depends on the number of valid convolutional kernels . To ensure effective feature extraction, the is defined as
where d represents the relative scaling factor for each pyramid level. The defines the reference kernel size for each pyramid level, ensuring consistent relative dimensions across scales and enabling effective multi-scale receptive fields, considering the deployment location of MAIE in the backbone network, the value of is 8. The lower bound of 3 is set as the minimum effective kernel size. Convolutional kernels smaller than are insufficient to capture local spatial structures, and may therefore provide limited feature representation. For the input feature map X, the output of the DDConv is calculated as:
where the offset of the deformable convolution (DConv) is predicted by the offset convolution layer, is the weight of the offset layer with a shape of , , and is the bias. Given the offset, is the output of the DConv module, and are convolution weight and bias. The final output of the (DDConv) module is obtained by multiplying the and the dynamic gating weight G, is the convolution, and is the sigmoid function.
and can enhance the mixed feature of the two modalities by element-wise multiplication to redistribute weights, which is able to highlight significant channels. At the same time, in order to increase the interactivity between modes and make each feature map of SAR and optical fully utilize the respective advantages of the other modality, we multiply and by the corresponding feature weights of the other modality on the basis of the redistribution of the channel weights of the respective modality to obtain semantic and texture information from the other modality:
where ⊙ is multiplication in channel dimension, ⊗ is element-wise multiplication.
For the SAR feature map and optical feature map , we use two atrous convolutions with different dilated rates, as a multi-scale atrous convolution (MAConv) module, to extract multi-scale pixel weights (MPE) and then concatenate them on channel dimensions:
where and two atrous convolution layers, and . For the mixed feature map , the cross-modality weight is obtained:
where refers to the feature compression operation:
where is the sigmoid-weighted linear unit, is the two-dimensional batch normalization, is a convolutional layer.
Then, we combine the attention mechanism and the gating mechanism, so that the model can process and adjust the features from multiple angles. We design a lightweight attention (LA) module to focus on the importance of local features to enhance modal-specific weights and , while the gating weight G regulates from the perspective of global features to enhance cross-modal weight . The two complement each other and further improve the feature expression ability of the model.
where are feature tensors after spatial flattening with being the number of spatial positions, normalization is applied along the (channel) axis, and the softmax operation is performed along the key-position axis. represents the mixed feature obtained through the cross-modal interaction enhancement (CIE) module after the fusion of and :
In practice, the MAIE module inherently embeds channel-spatial interaction and stability mechanisms within its design. The multi-scale convolutional branches dynamically adapt receptive fields and channel reweighting to maintain spatial consistency and balance feature magnitudes. Meanwhile, lightweight gated operations regularize attention responses and prevent activation saturation. During cross-modal fusion, depthwise convolutions with sigmoid gating ensure consistent channel distribution and suppress gradient oscillations. Together, these mechanisms stabilize multi-stage attention learning and effectively mitigate feature-distribution drift during training.
3.3. Multi-Direction Focus
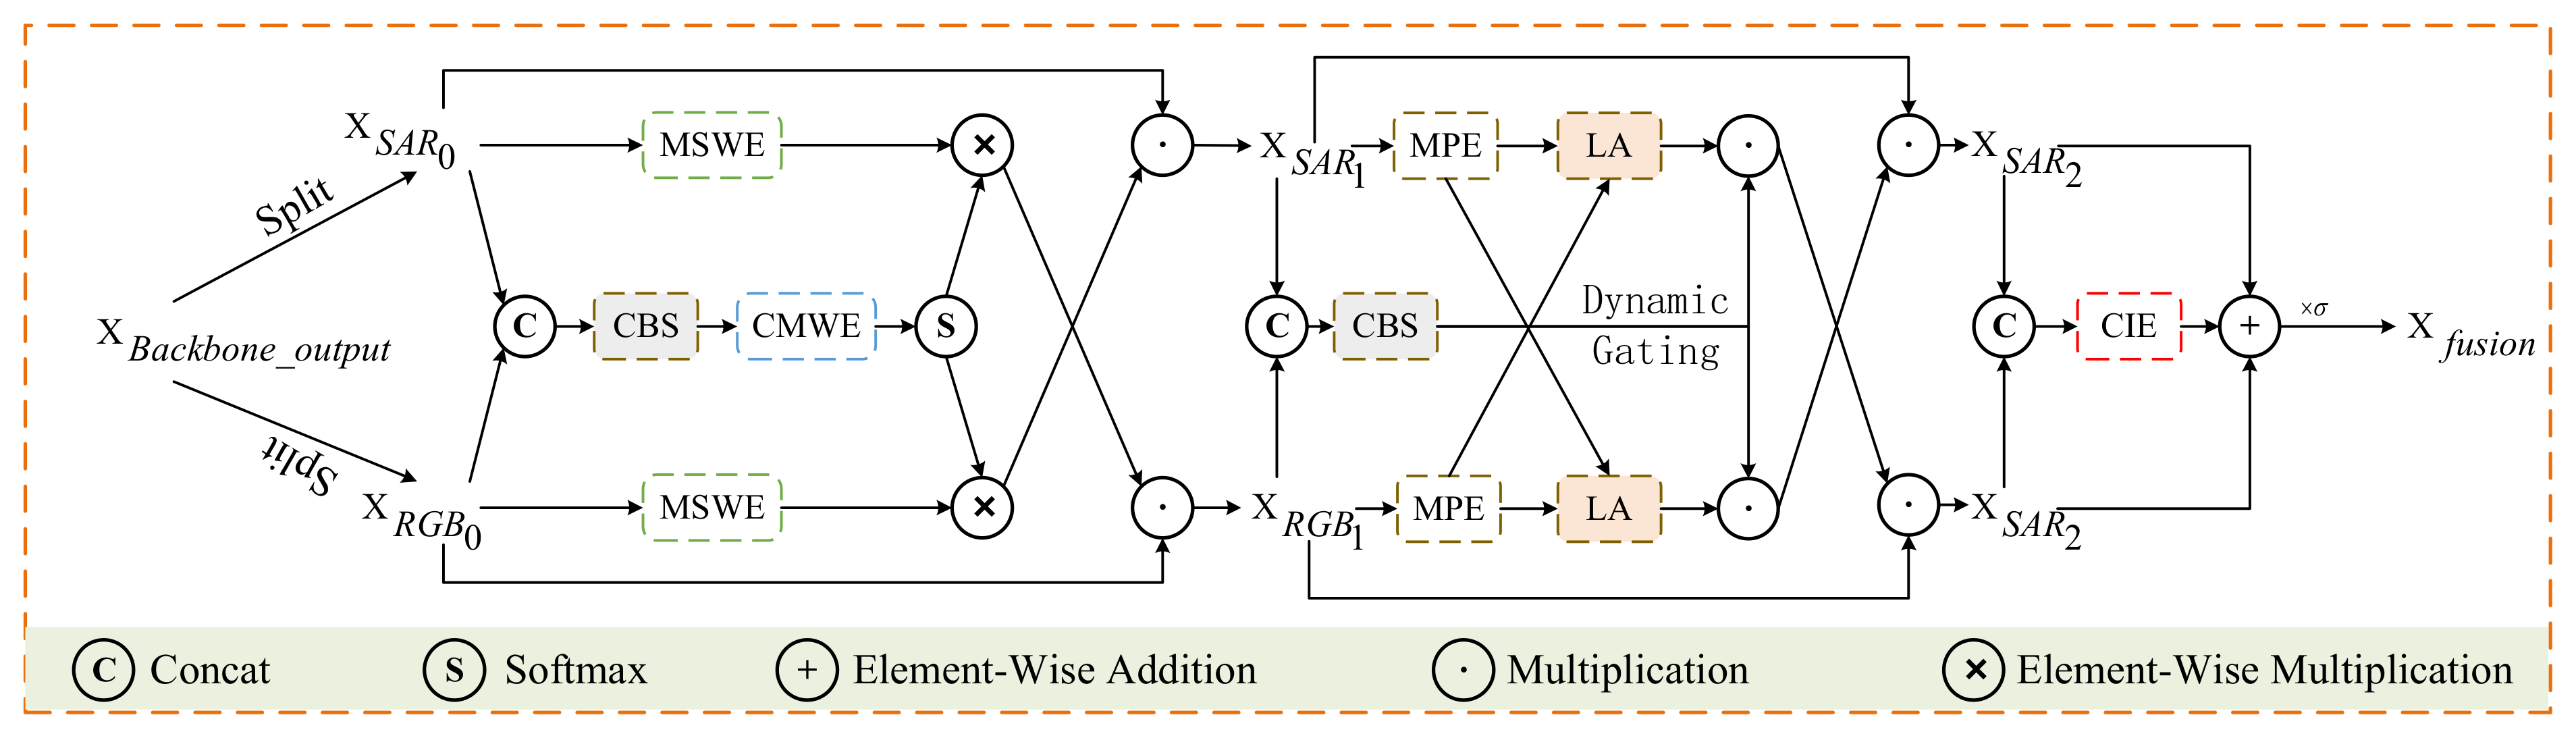
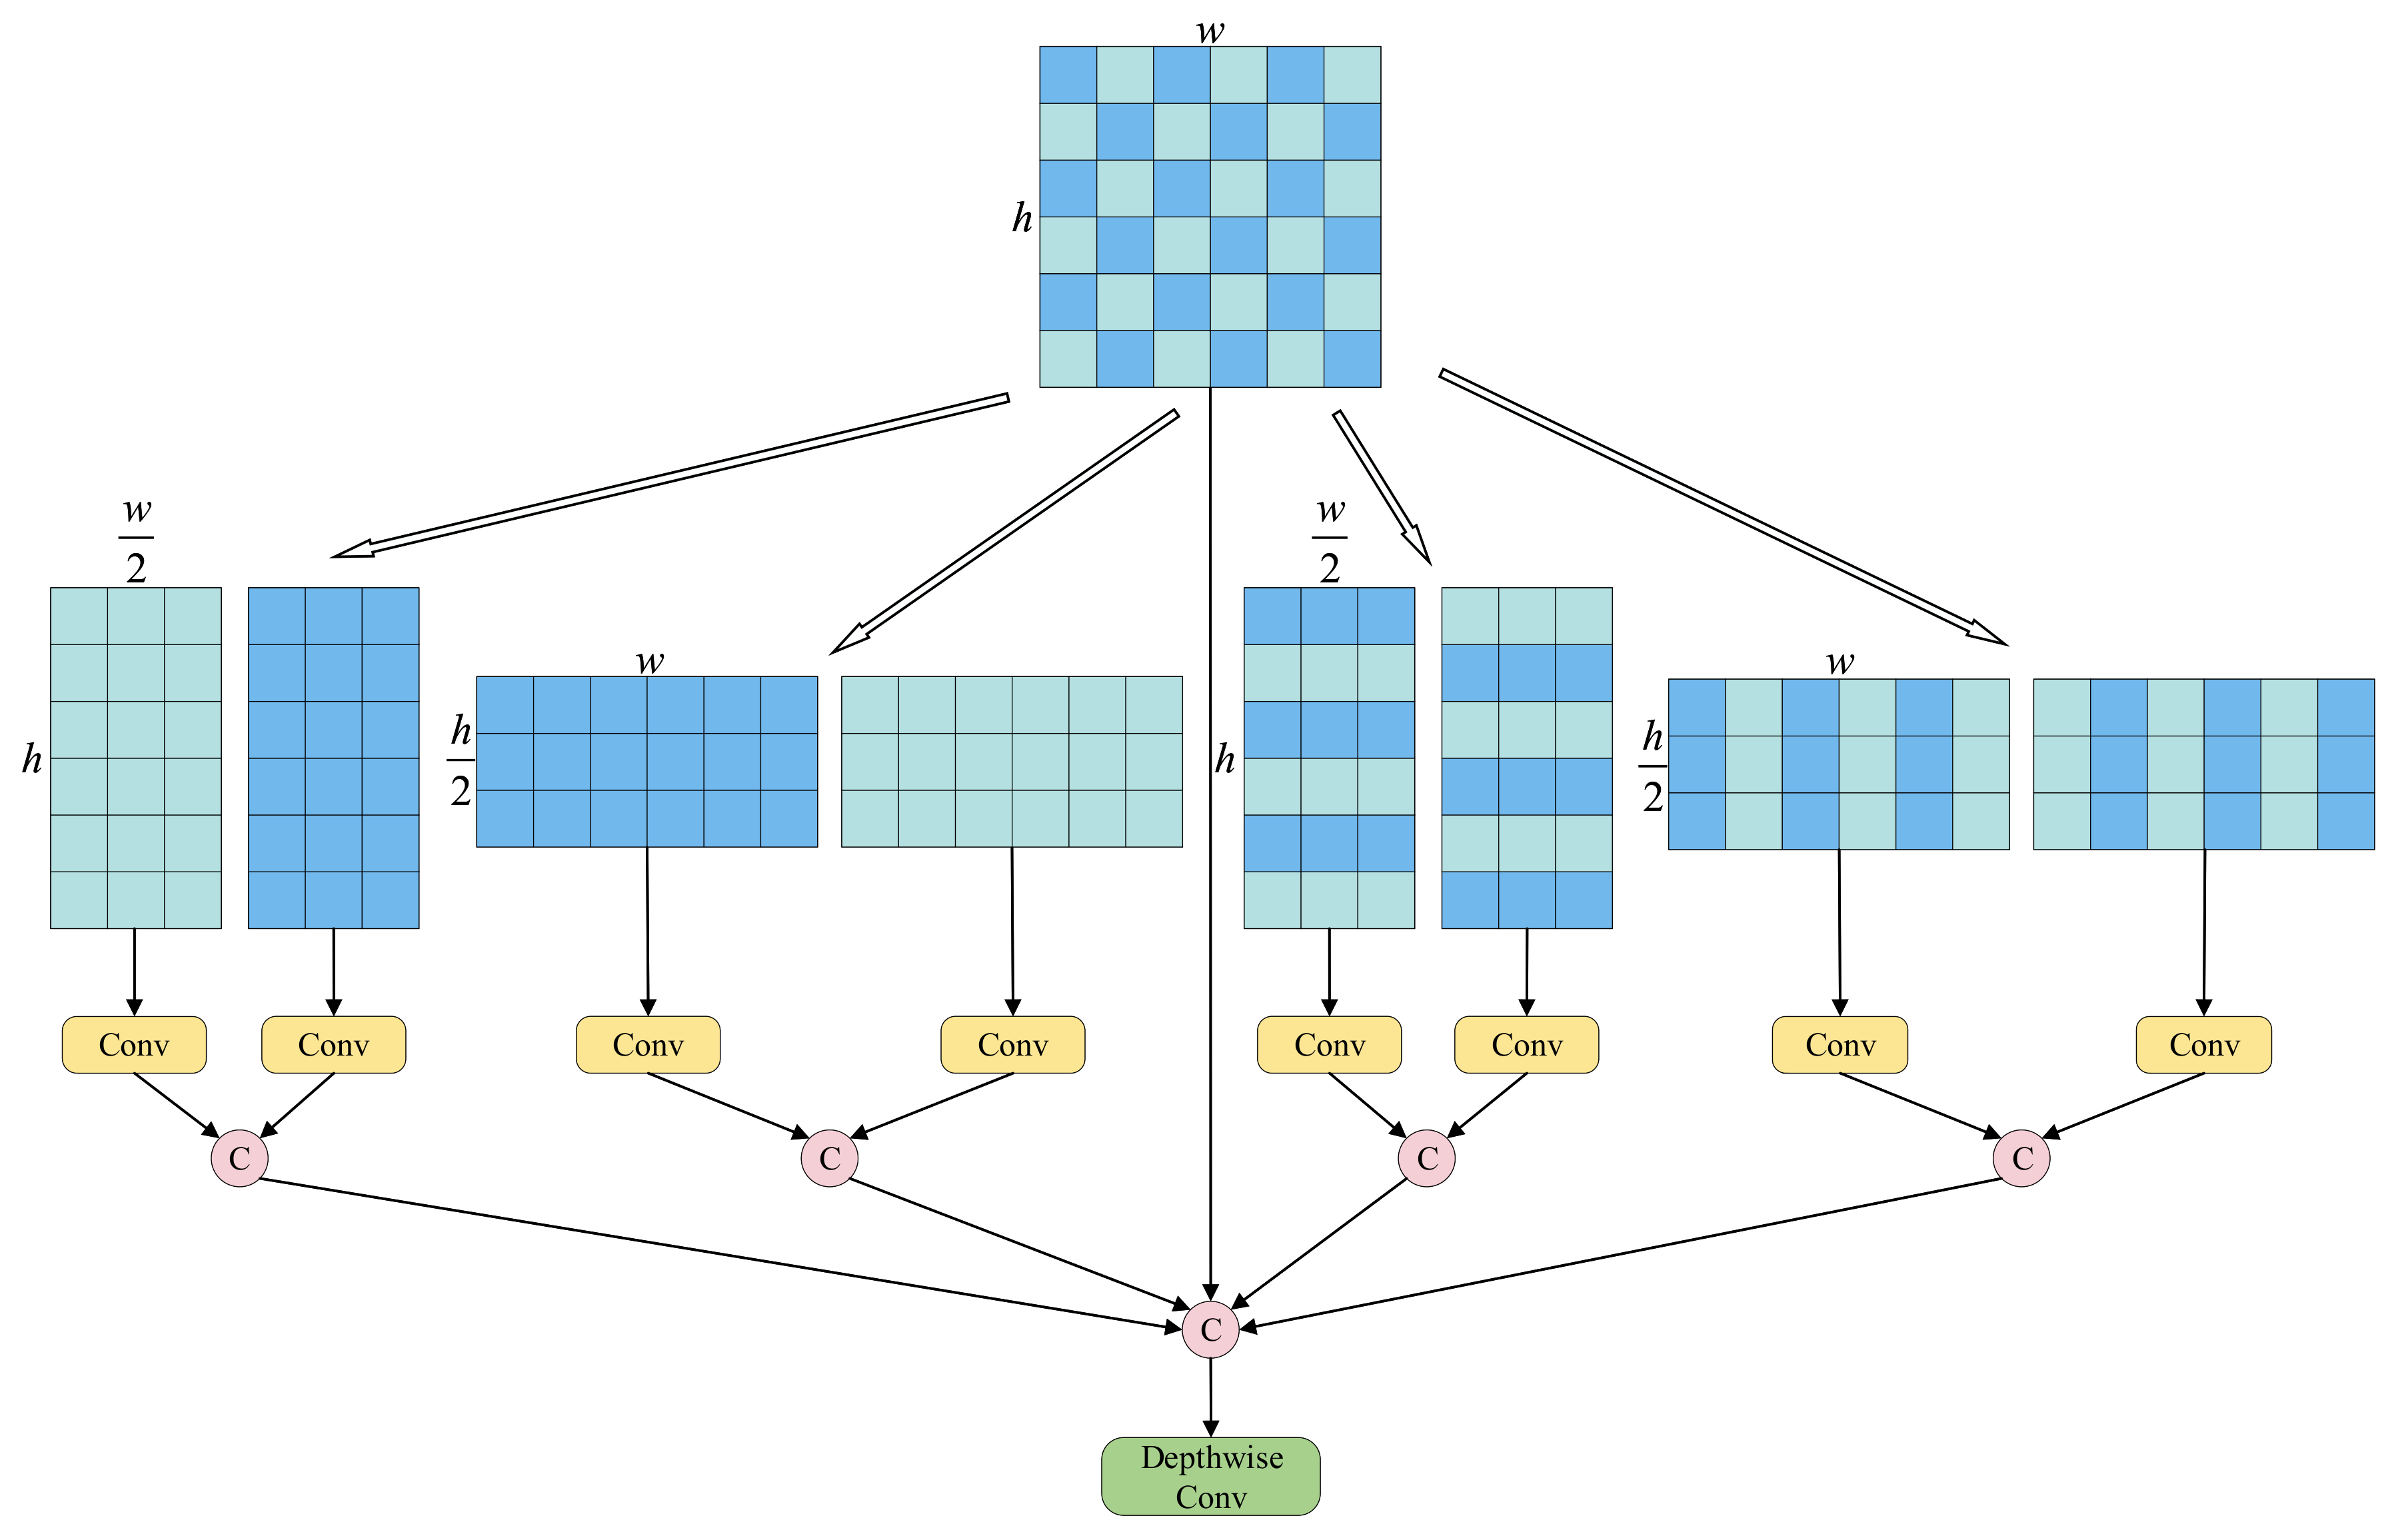
The proposed MF module aims to enlarge the effective receptive field while preserving orientation-specific contextual information (Figure 4). It is integrated at the second stage of the backbone. Unlike conventional isotropic convolution, MF decomposes the input into multiple orientation-aware subspaces, enabling the capture of structured spatial dependencies in different geometric directions.
Figure 4.
Architecture of the Multi-direction Focus module. Four orientation-specific branches operate on the input feature map, followed by channel-wise concatenation and depthwise separable integration.
Given an input feature map , four independent directional transformations are defined:
- : horizontal orientation, emphasizing row-wise structures.
- : vertical orientation, emphasizing column-wise structures.
- : main-diagonal orientation, preserving principal diagonal correlations.
- : anti-diagonal orientation, preserving the inverse diagonal patterns.
Each branch applies a deterministic sampling operator followed by two convolutional mappings:
where ⊕ denotes element-wise assignment into the spatial positions corresponding to the original orientation. The sampling operators and partition the input along the given directional axis, ensuring that the subsequent convolutions process spatially coherent sub-maps.
The outputs of the four orientation-specific branches, together with the original X, are concatenated along the channel dimension:
Integration is achieved via a depthwise separable convolution:
For the MF module, a residual-guided normalization path regularizes multi-stage attention updates by aligning feature distributions and mitigating activation saturation. Together, these mechanisms stabilize the training process, minimize feature-distribution drift, and ensure robust convergence even under deep attention stacking.
4. Experiments and Results
4.1. Datasets
To assess the effectiveness of the proposed MAIENet framework, experiments were carried out on the newly released OGSOD-1.0 [19] dataset. Unlike conventional SAR datasets that are limited to a single modality, OGSOD-1.0 is constructed for multimodal object detection under realistic and challenging conditions. The dataset comprises strictly co-registered SAR-optical image pairs covering diverse geographic environments, thereby facilitating a comprehensive investigation into the complementary characteristics of the two modalities. SAR data were acquired by the Chinese GaoFen-3 satellite (C-band) in vertical–vertical (VV) and vertical–horizontal (VH) polarization modes, with a spatial resolution of 3 m, provided by the 38th Research Institute of China Electronics Technology Group Corporation. The corresponding optical images were obtained from Google Earth at a spatial resolution of 10 m, precisely matched to the SAR scenes. To minimize temporal decorrelation, optical imagery was selected within one month of the SAR acquisition date, based on geolocation and acquisition timestamps. Both modalities were resampled to a common spatial resolution using ENVI software, geometrically aligned, and cropped into patches of pixels prior to annotation.
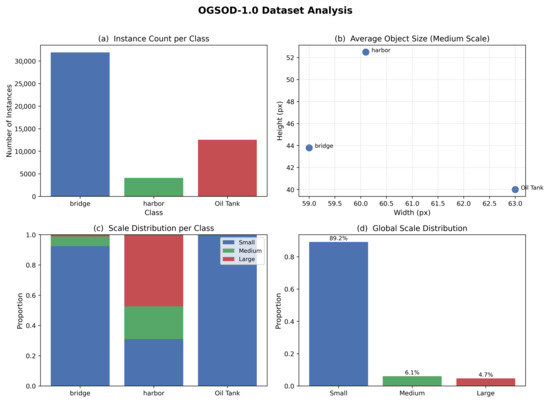
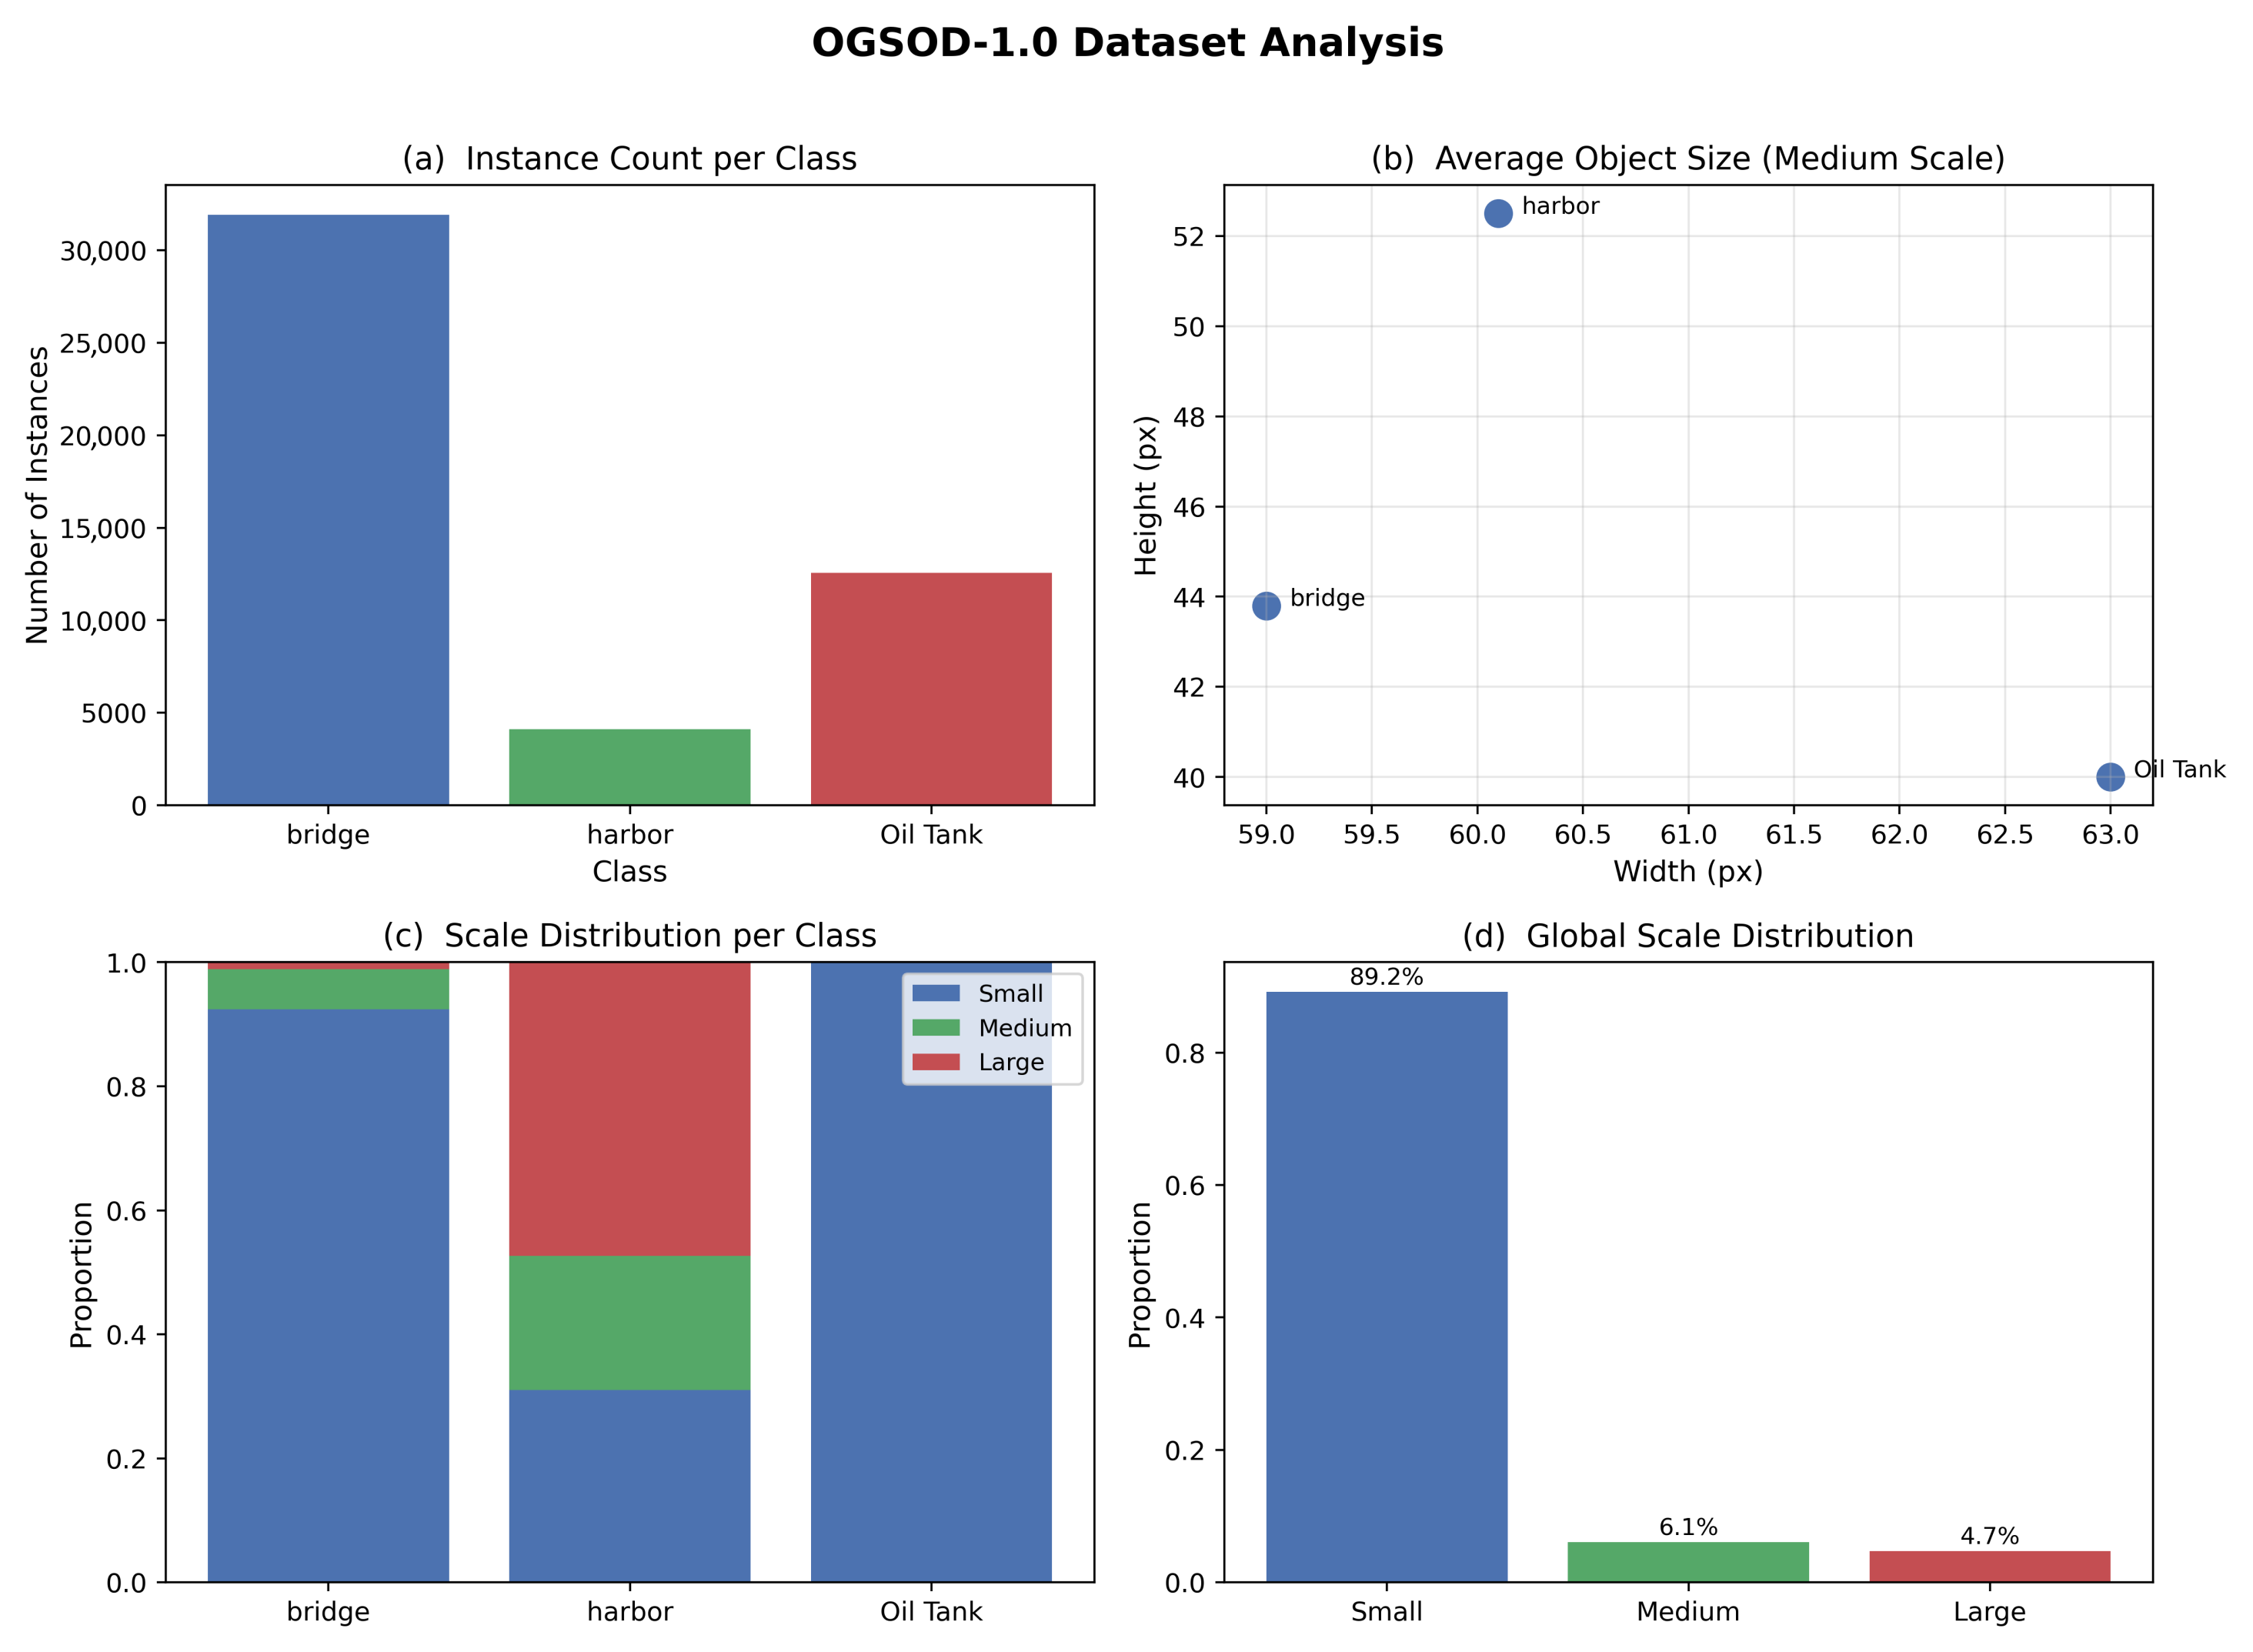
The training set consists of 14,665 SAR-optical pairs, while the test set contains 3666 SAR-optical pairs. In total, OGSOD-1.0 includes three static target categories: bridges (31,922 instances), harbors (4109 instances), and storage tanks (12,558 instances). Statistical analysis reveals that approximately 90% of all annotated objects have dimensions smaller than pixels, posing significant challenges for small-object detection. The instance distribution and object size statistics are illustrated in Figure 5. For each category (bridge, harbor, oil tank), we compute the real object width, height, and area in pixel units, then classifies them into three scale levels according to their actual area: small (0–2% of image area), medium (2–8%), and large (8–100%).
Figure 5.
Statistical analysis of the OGSOD-1.0 dataset. (a) Instance distribution across three categories: bridge, harbor, and oil tank. (b) Distribution of average target sizes (represented by medium scale) across categories. (c) Scale proportion of each category. (d) Global scale distribution across all categories.
4.2. Experimental Environment
All experiments in this study were conducted on the OGSOD-1.0 dataset. The training was performed for 400 epochs with a batch size of 32, using uniformly resized input images of pixels. The model parameters were optimized using the Stochastic Gradient Descent (SGD) algorithm with an initial learning rate of 0.01, a momentum of 0.9, and a weight decay of 0.0005. All models are trained on an NVIDIA 3090 GPU. We employ the Average Precision (AP) and Mean Average Precision (mAP) to evaluate the performance of the target detector. True positives (TP) and false positives (FP) were determined by Intersection over Union (IoU) thresholds. For a more detailed assessment, we set the IoU thresholds to 0.5 and 0.50:0.95, respectively, resulting in the , and indicators.
4.3. Results
4.3.1. Comparison with Advanced Detectors
To ensure fairness, methods are grouped by modality: single-modal SAR, single-modal RGB, cross-modal KD-based, and multimodal fusion-based, as summarized in Table 1. Baselines are consistent within each category: all KD-based methods (KD, LD, CoLD) adopt YOLOv5 as backbone; CSSA, CMADet, ICAFusion, and our MAIENet adopt YOLOv11 as backbone; and DEYOLOm adopts YOLOv8 as backbone. Compared with single-modal approaches, MAIENet achieves consistently superior detection accuracy. Relative to the strongest single-modal SAR baseline, CoDeSAR, MAIENet improves and by 3.4% and 4.2%, respectively, while reducing parameter count by 11.9 M (25.9%). Notable gains are observed in all categories, especially for Oil Tank detection ( up to 79.0%). Within KD-based cross-modal methods, MAIENet surpasses the strongest competitor, CoLD, by 3.2% in and 4.3% in , alongside a reduction of 52.2 M parameters (60.6%). Against the latest multimodal fusion baseline DEYOLOm, MAIENet achieves improvements of 1.1% in and 1.5% in , while being more compact with 14.7 M fewer parameters.These results indicate that MAIENet’s performance gains derive primarily from its enhanced cross-modal interaction (via BSCC, MAIE, and MF modules) and receptive field aggregation, rather than from expanded model capacity. The balanced trade-off between accuracy and compactness makes MAIENet suitable for deployment in computationally constrained scenarios.
Table 1.
Comparison results with advanced detectors on OGSOD-1.0 dataset. The models are grouped by modality type: single-modal SAR, single-modal RGB, cross-modal (KD-based), and multimodal (fusion-based). The best results are in bold.
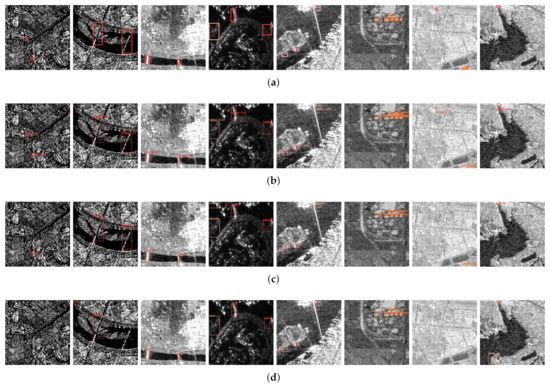
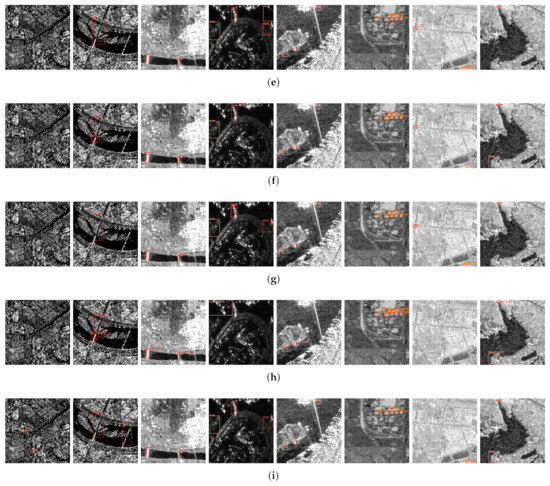
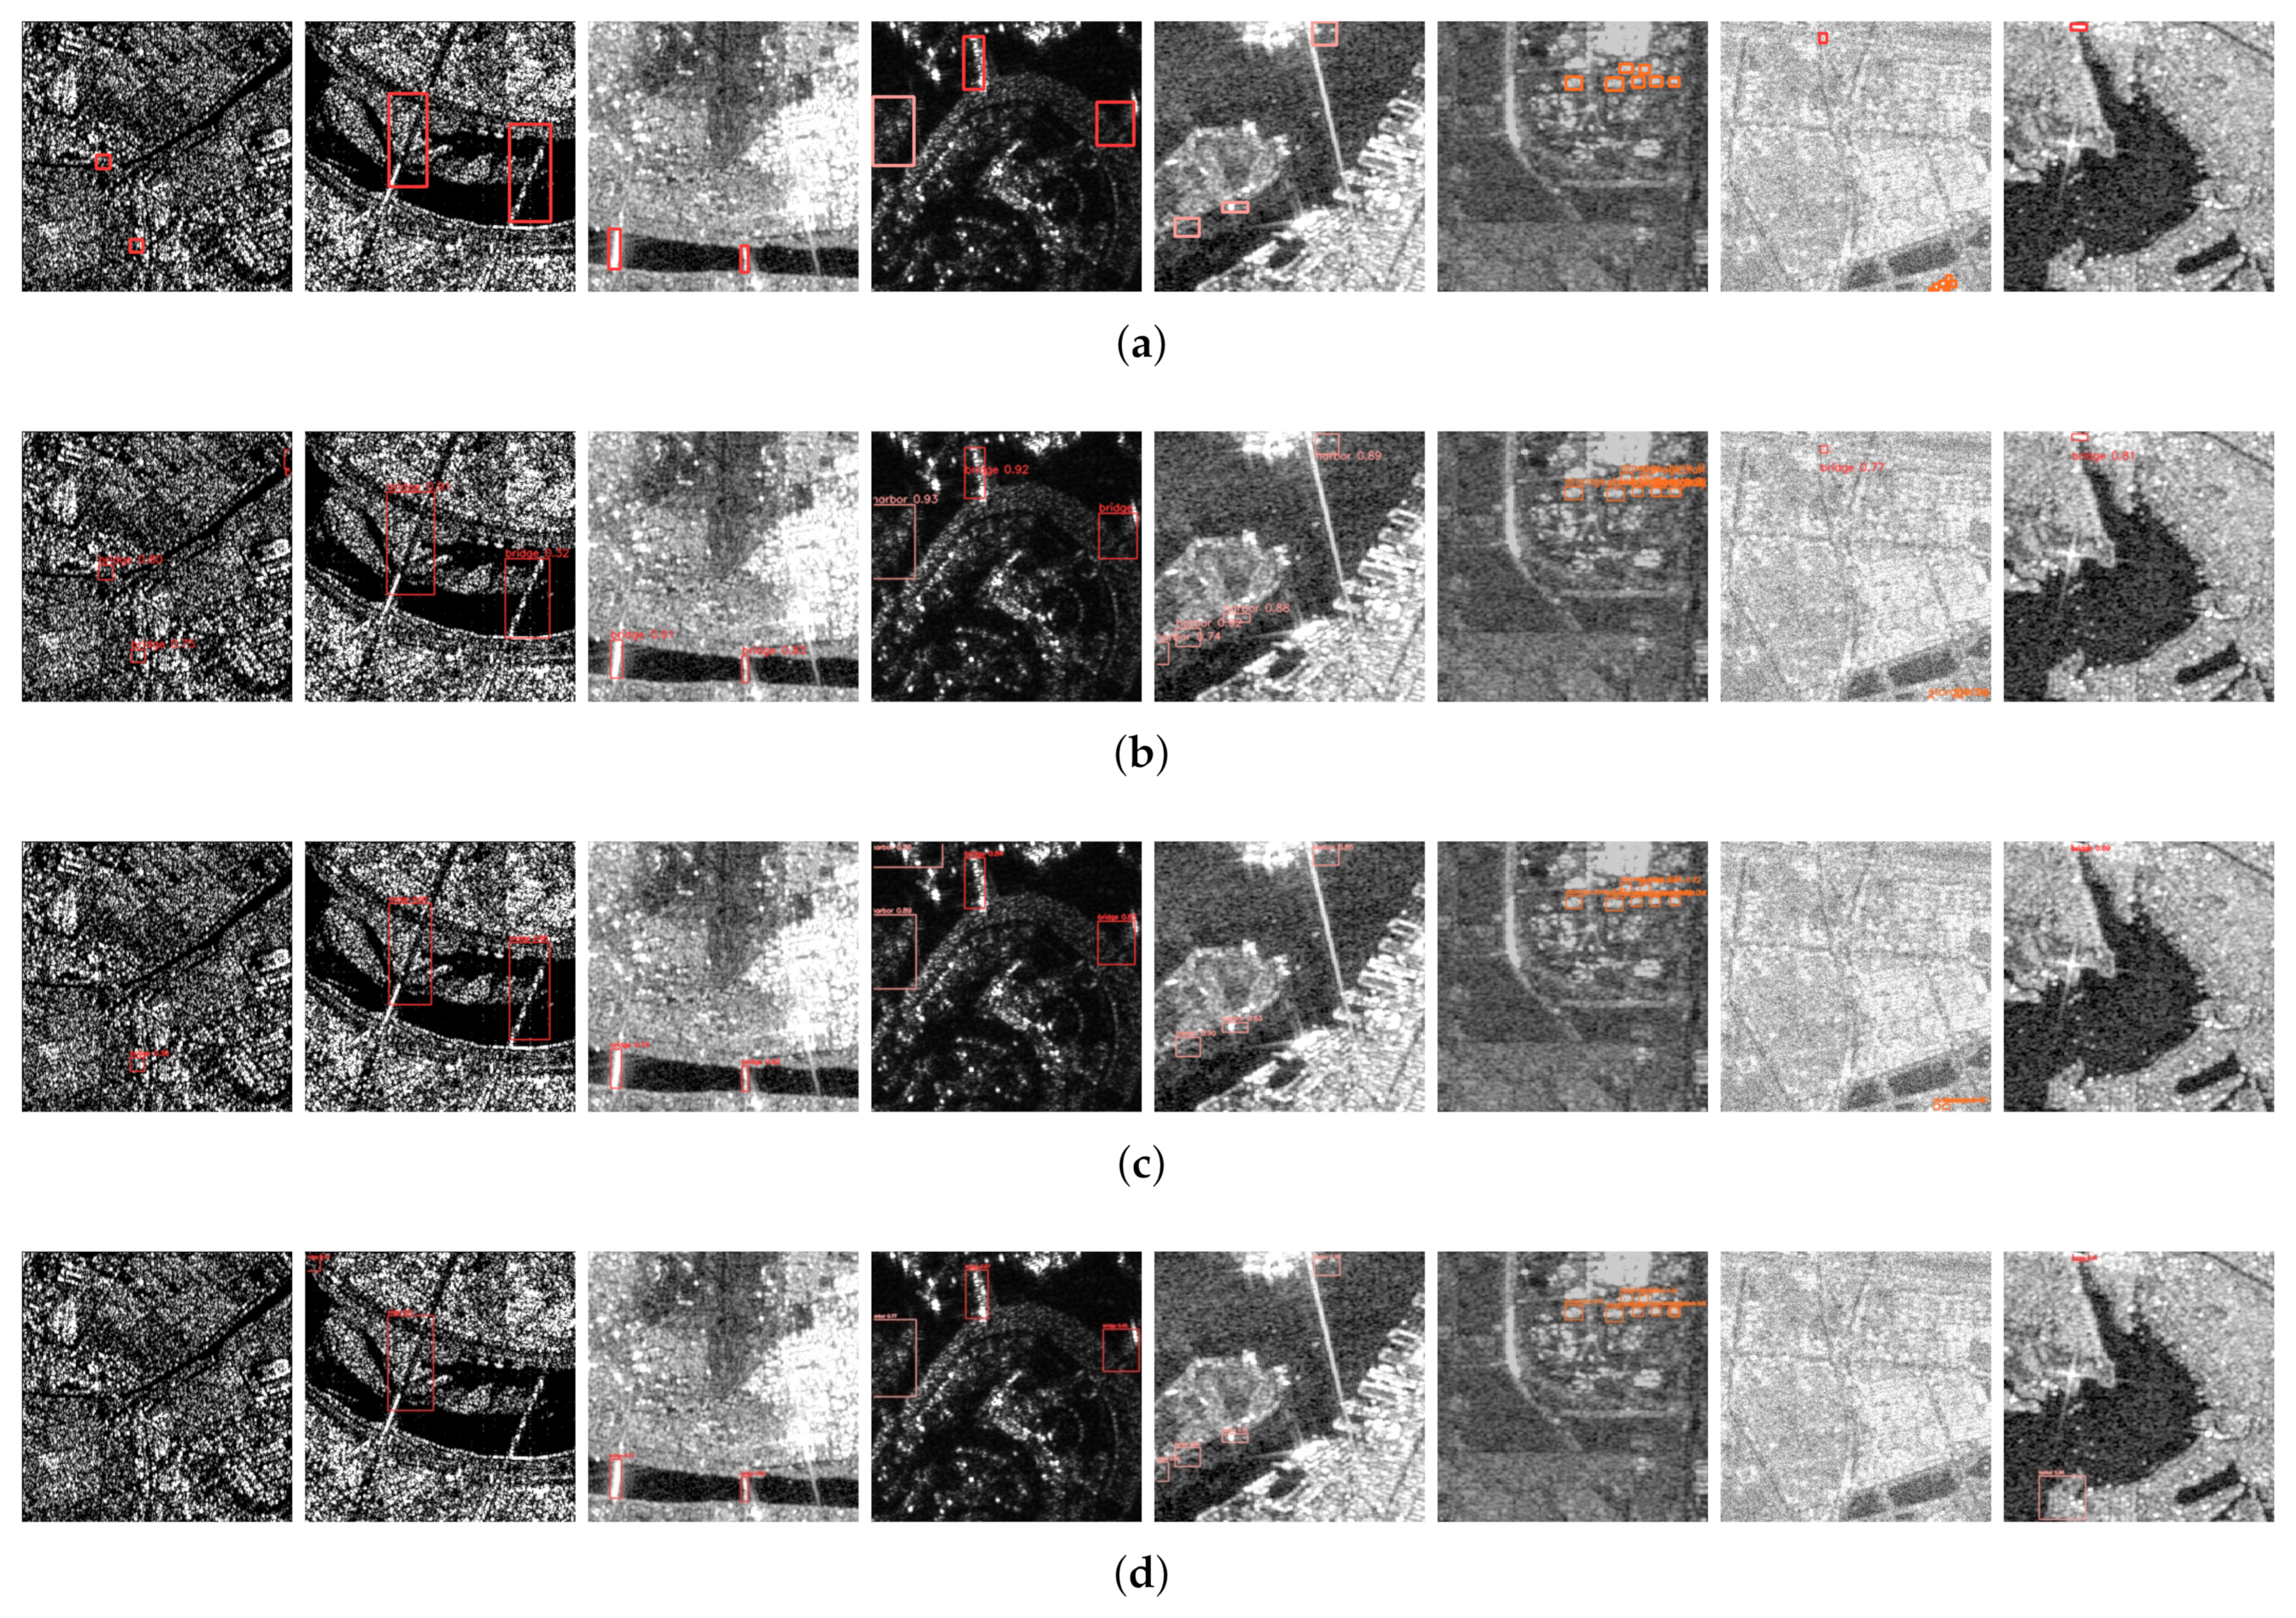
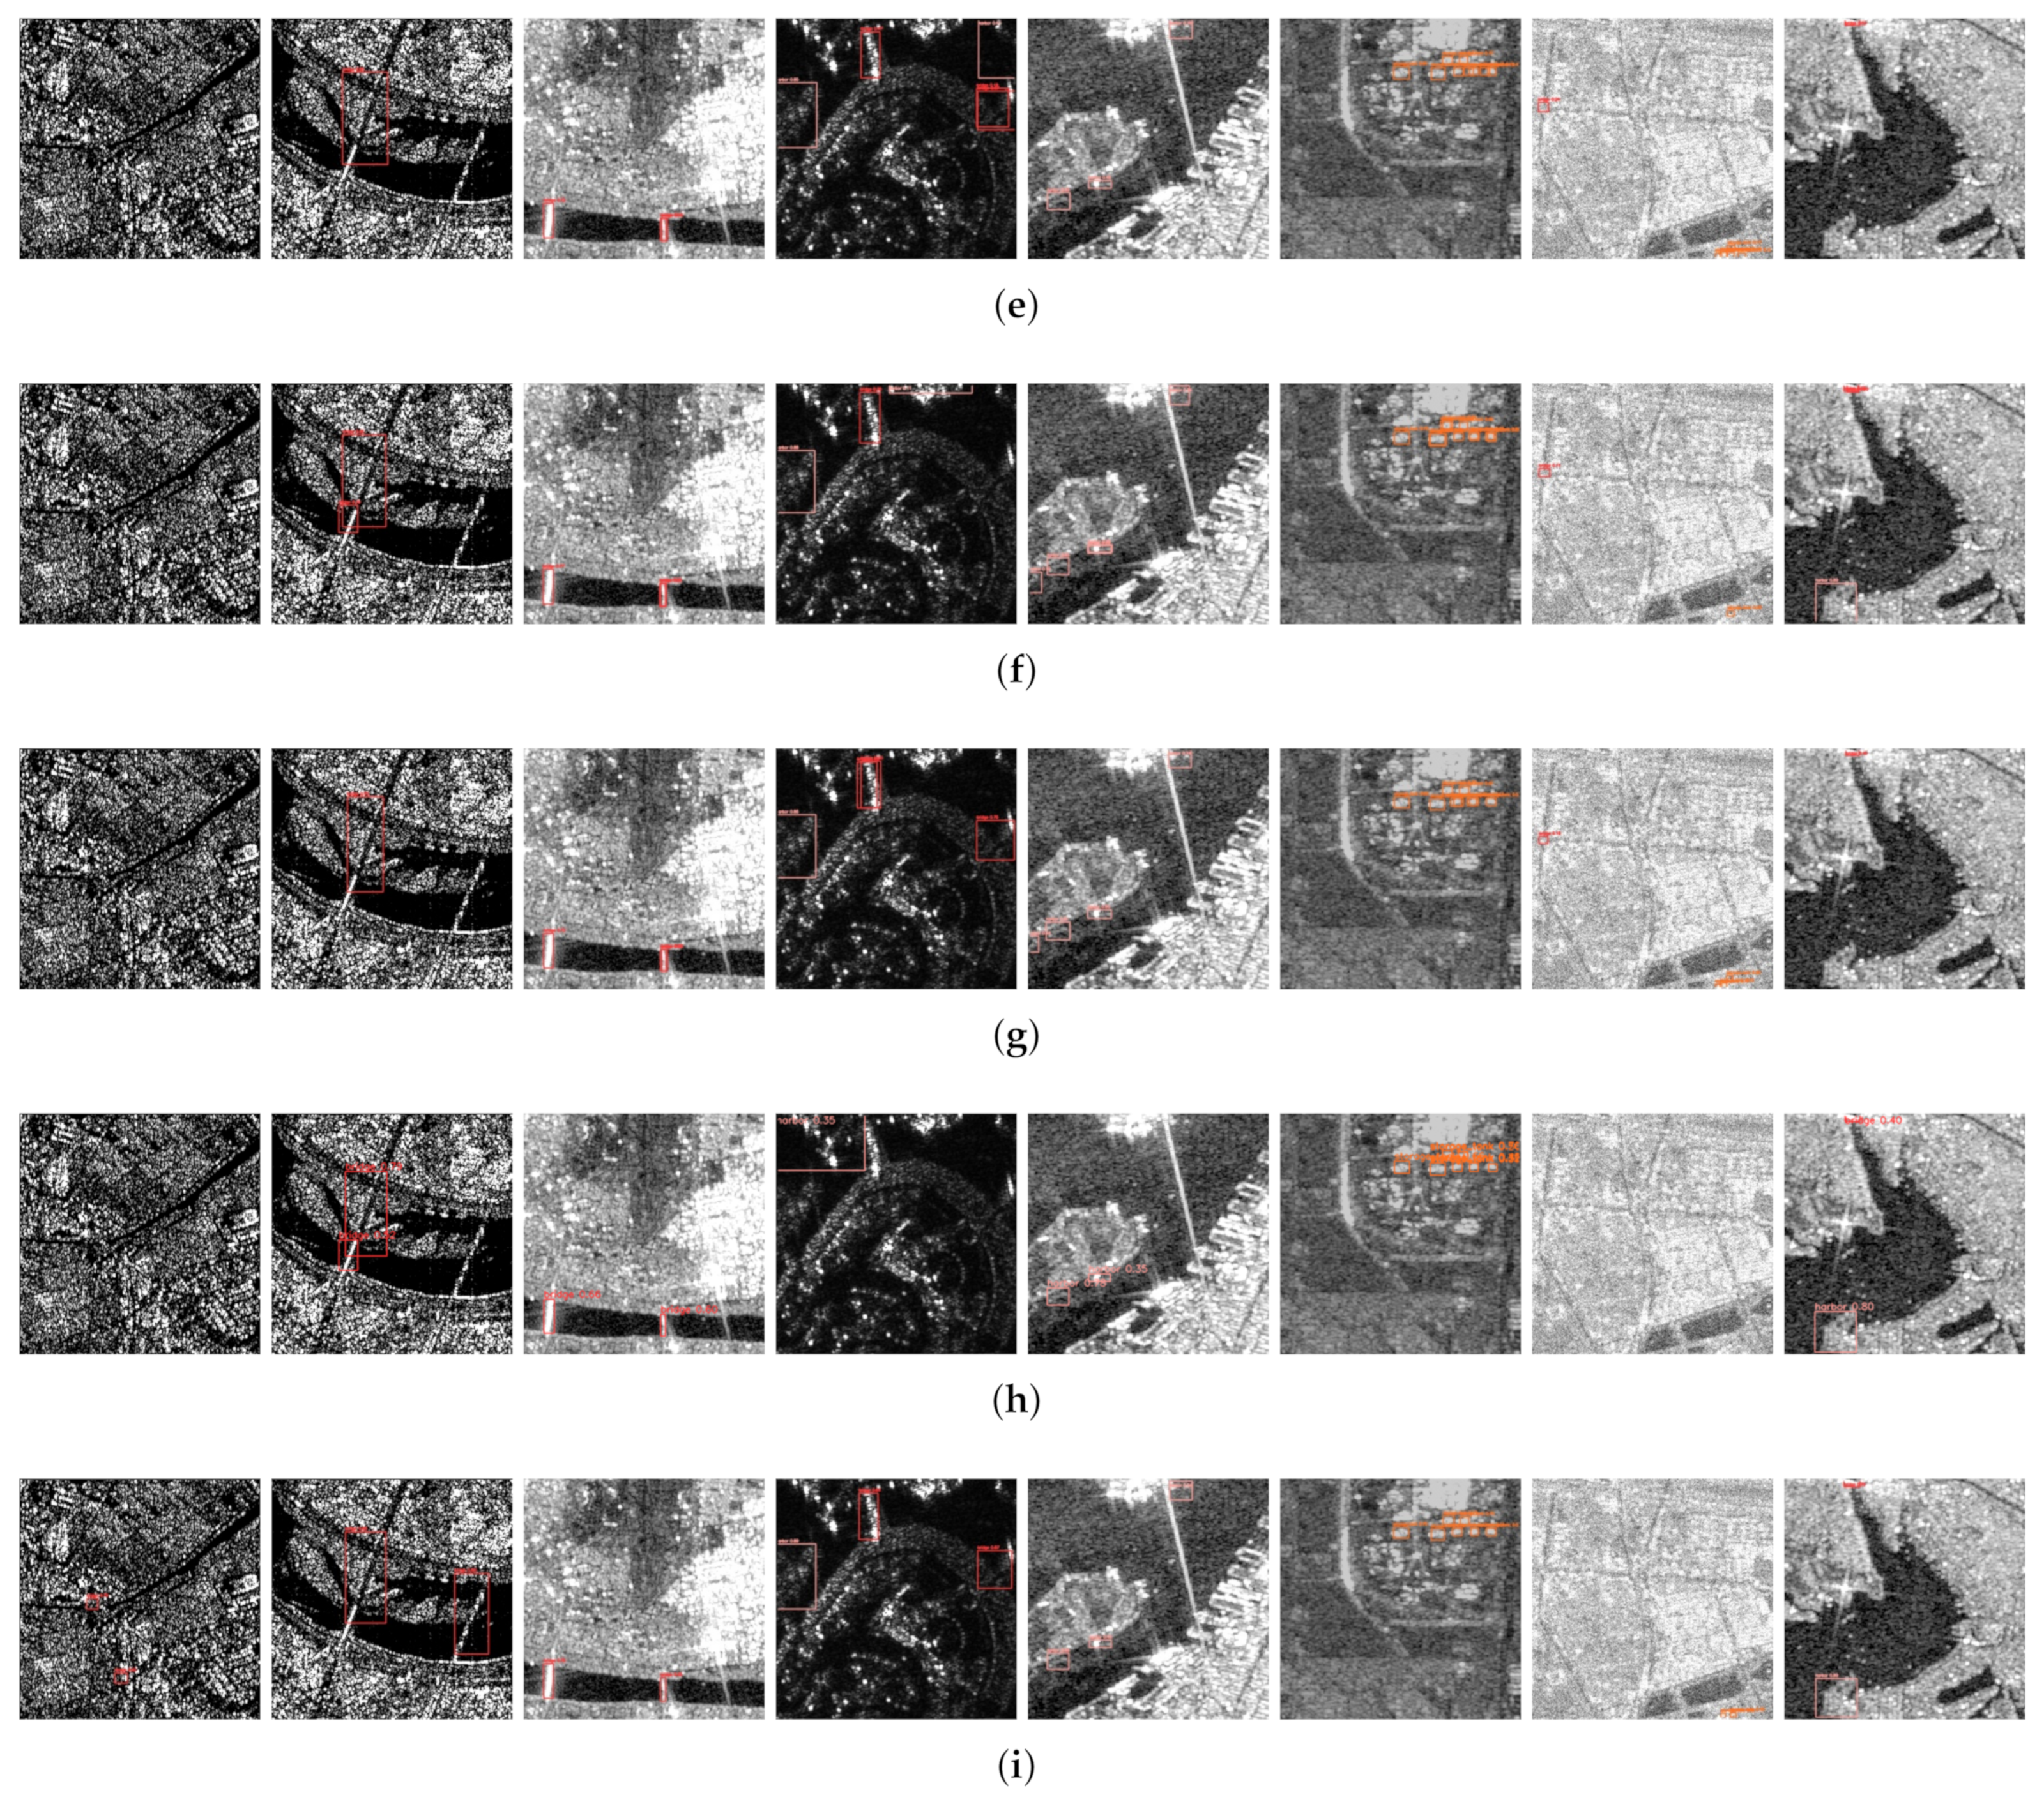
As illustrated in Figure 6, MAIENet demonstrates not only strong performance on the metric but also substantial improvements in detection quality. Benefiting from the BSCC module’s explicit separation and channel-consistent fusion of SAR and optical features, the MAIE module’s adaptive cross-modal enhancement through channel reweighting, deformable pyramid convolutions, and attention-guided interaction, and the MF module’s multi-directional receptive field aggregation, our MAIENet is able to capture richer semantic and texture cues across modalities. This leads to more discriminative representations that effectively suppress both missed and false detections.
Figure 6.
Visualization of detection results for different comparison methods. (a) Raw images with annotated ground truth. (b) Results of CoLD. (c) Results of DEYOLOm. (d) Results of YOLOv8m. (e) Results of YOLOv9m. (f) Results of YOLOv10m. (g) Results of YOLOv11m. (h) Results of YOLOv12m. (i) Results of the proposed MAIENet.
From the first two columns on the left, MAIENet achieves precise identification of targets, whereas single-modal detectors (YOLOv8m, YOLOv9m, YOLOv10m, YOLOv11m, YOLOv12m) consistently exhibit missed detections. Multimodal baselines such as DEYOLOm and CoLD detect most targets, yet still suffer from inaccuracies due to insufficient fine-grained cross-modal alignment. Particularly for small objects adjacent to shorelines, where SAR returns are noisy and boundaries are indistinct, MAIENet maintains robust recognition—as shown in the fifth column on the left—demonstrating the efficacy of MF-enhanced spatial context in challenging conditions.
Although a few false positives and missed detections are present in the last two columns, the visual comparisons clearly indicate a substantial gain over the baseline YOLOv11m. Overall, these visualization results confirm that MAIENet effectively leverages modality-complementary information, transforming heterogeneous SAR-optical inputs into high-quality unified embeddings for superior object localization and classification.
4.3.2. Baseline Model Selection
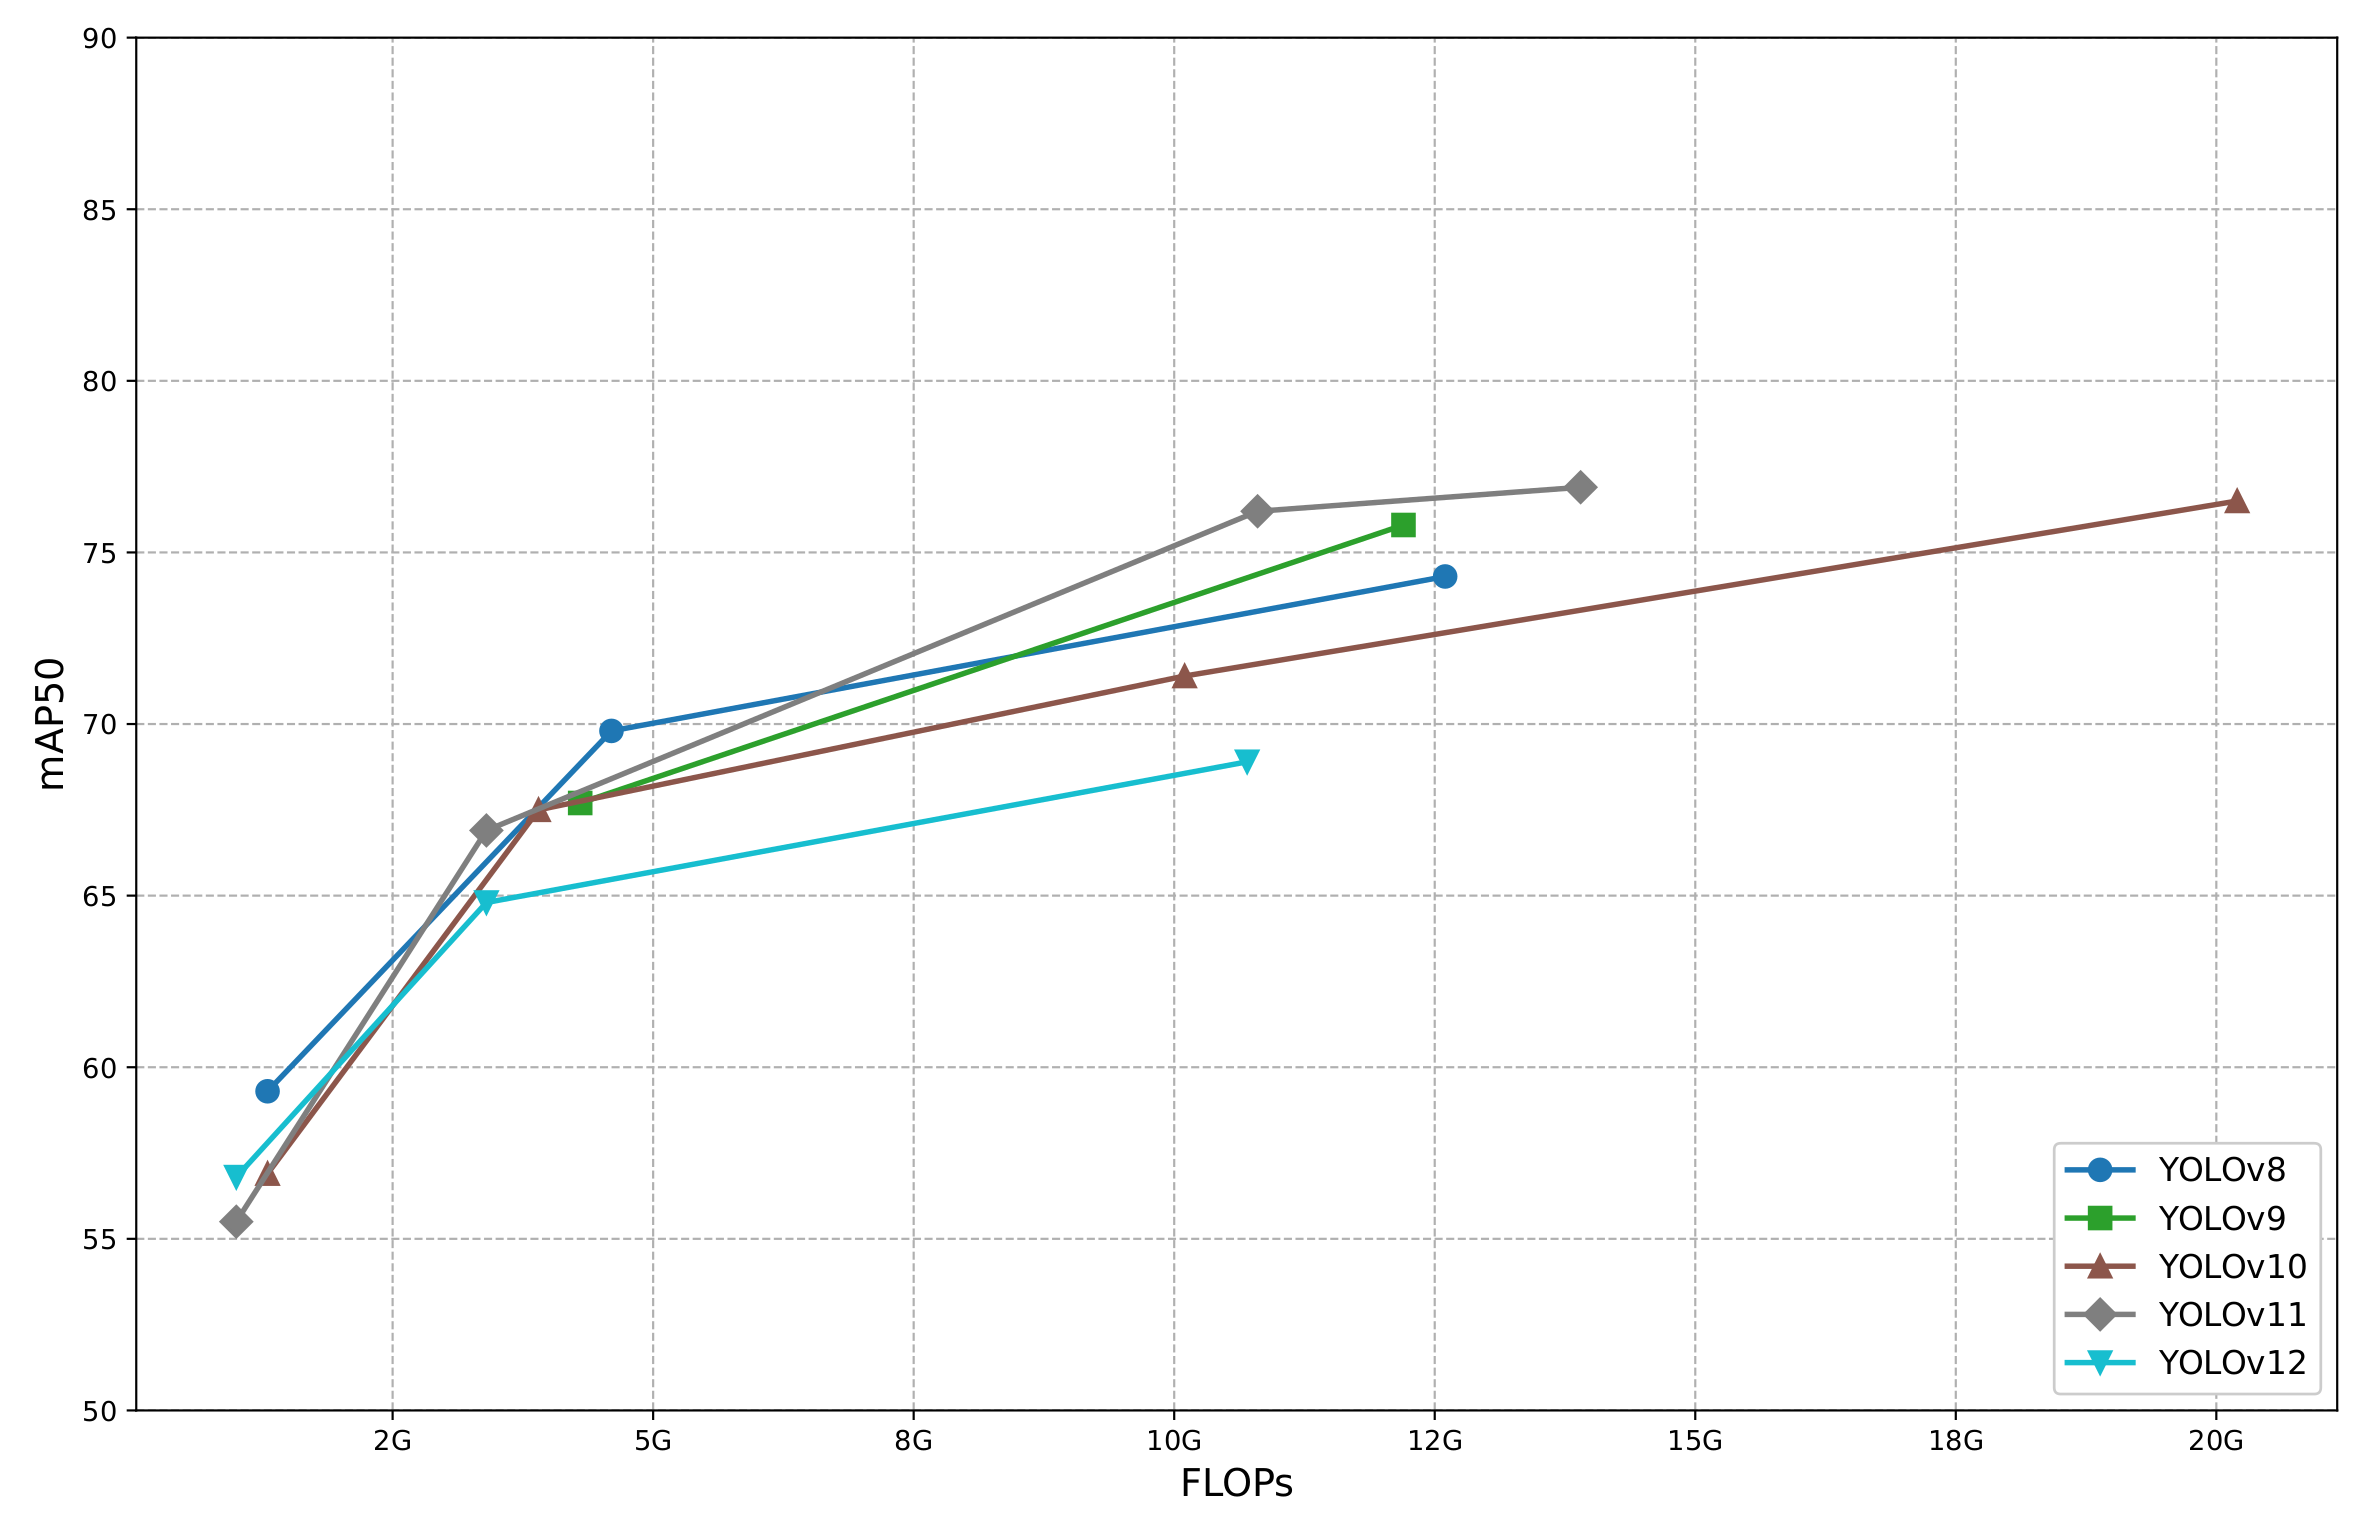
As illustrated in Figure 7, we evaluated the proposed model against advanced YOLO series models. The experimental results indicate that, among models operating at the 10G FLOPs level, YOLOv11 achieves higher detection accuracy, whereas YOLOv10 requires nearly twice the computational cost to attain comparable performance. Consequently, YOLOv11 is selected as the baseline model due to its lower computational complexity and greater deployment efficiency.
Figure 7.
Comparative analysis curves of different advanced detectors.
4.3.3. Ablation Studies
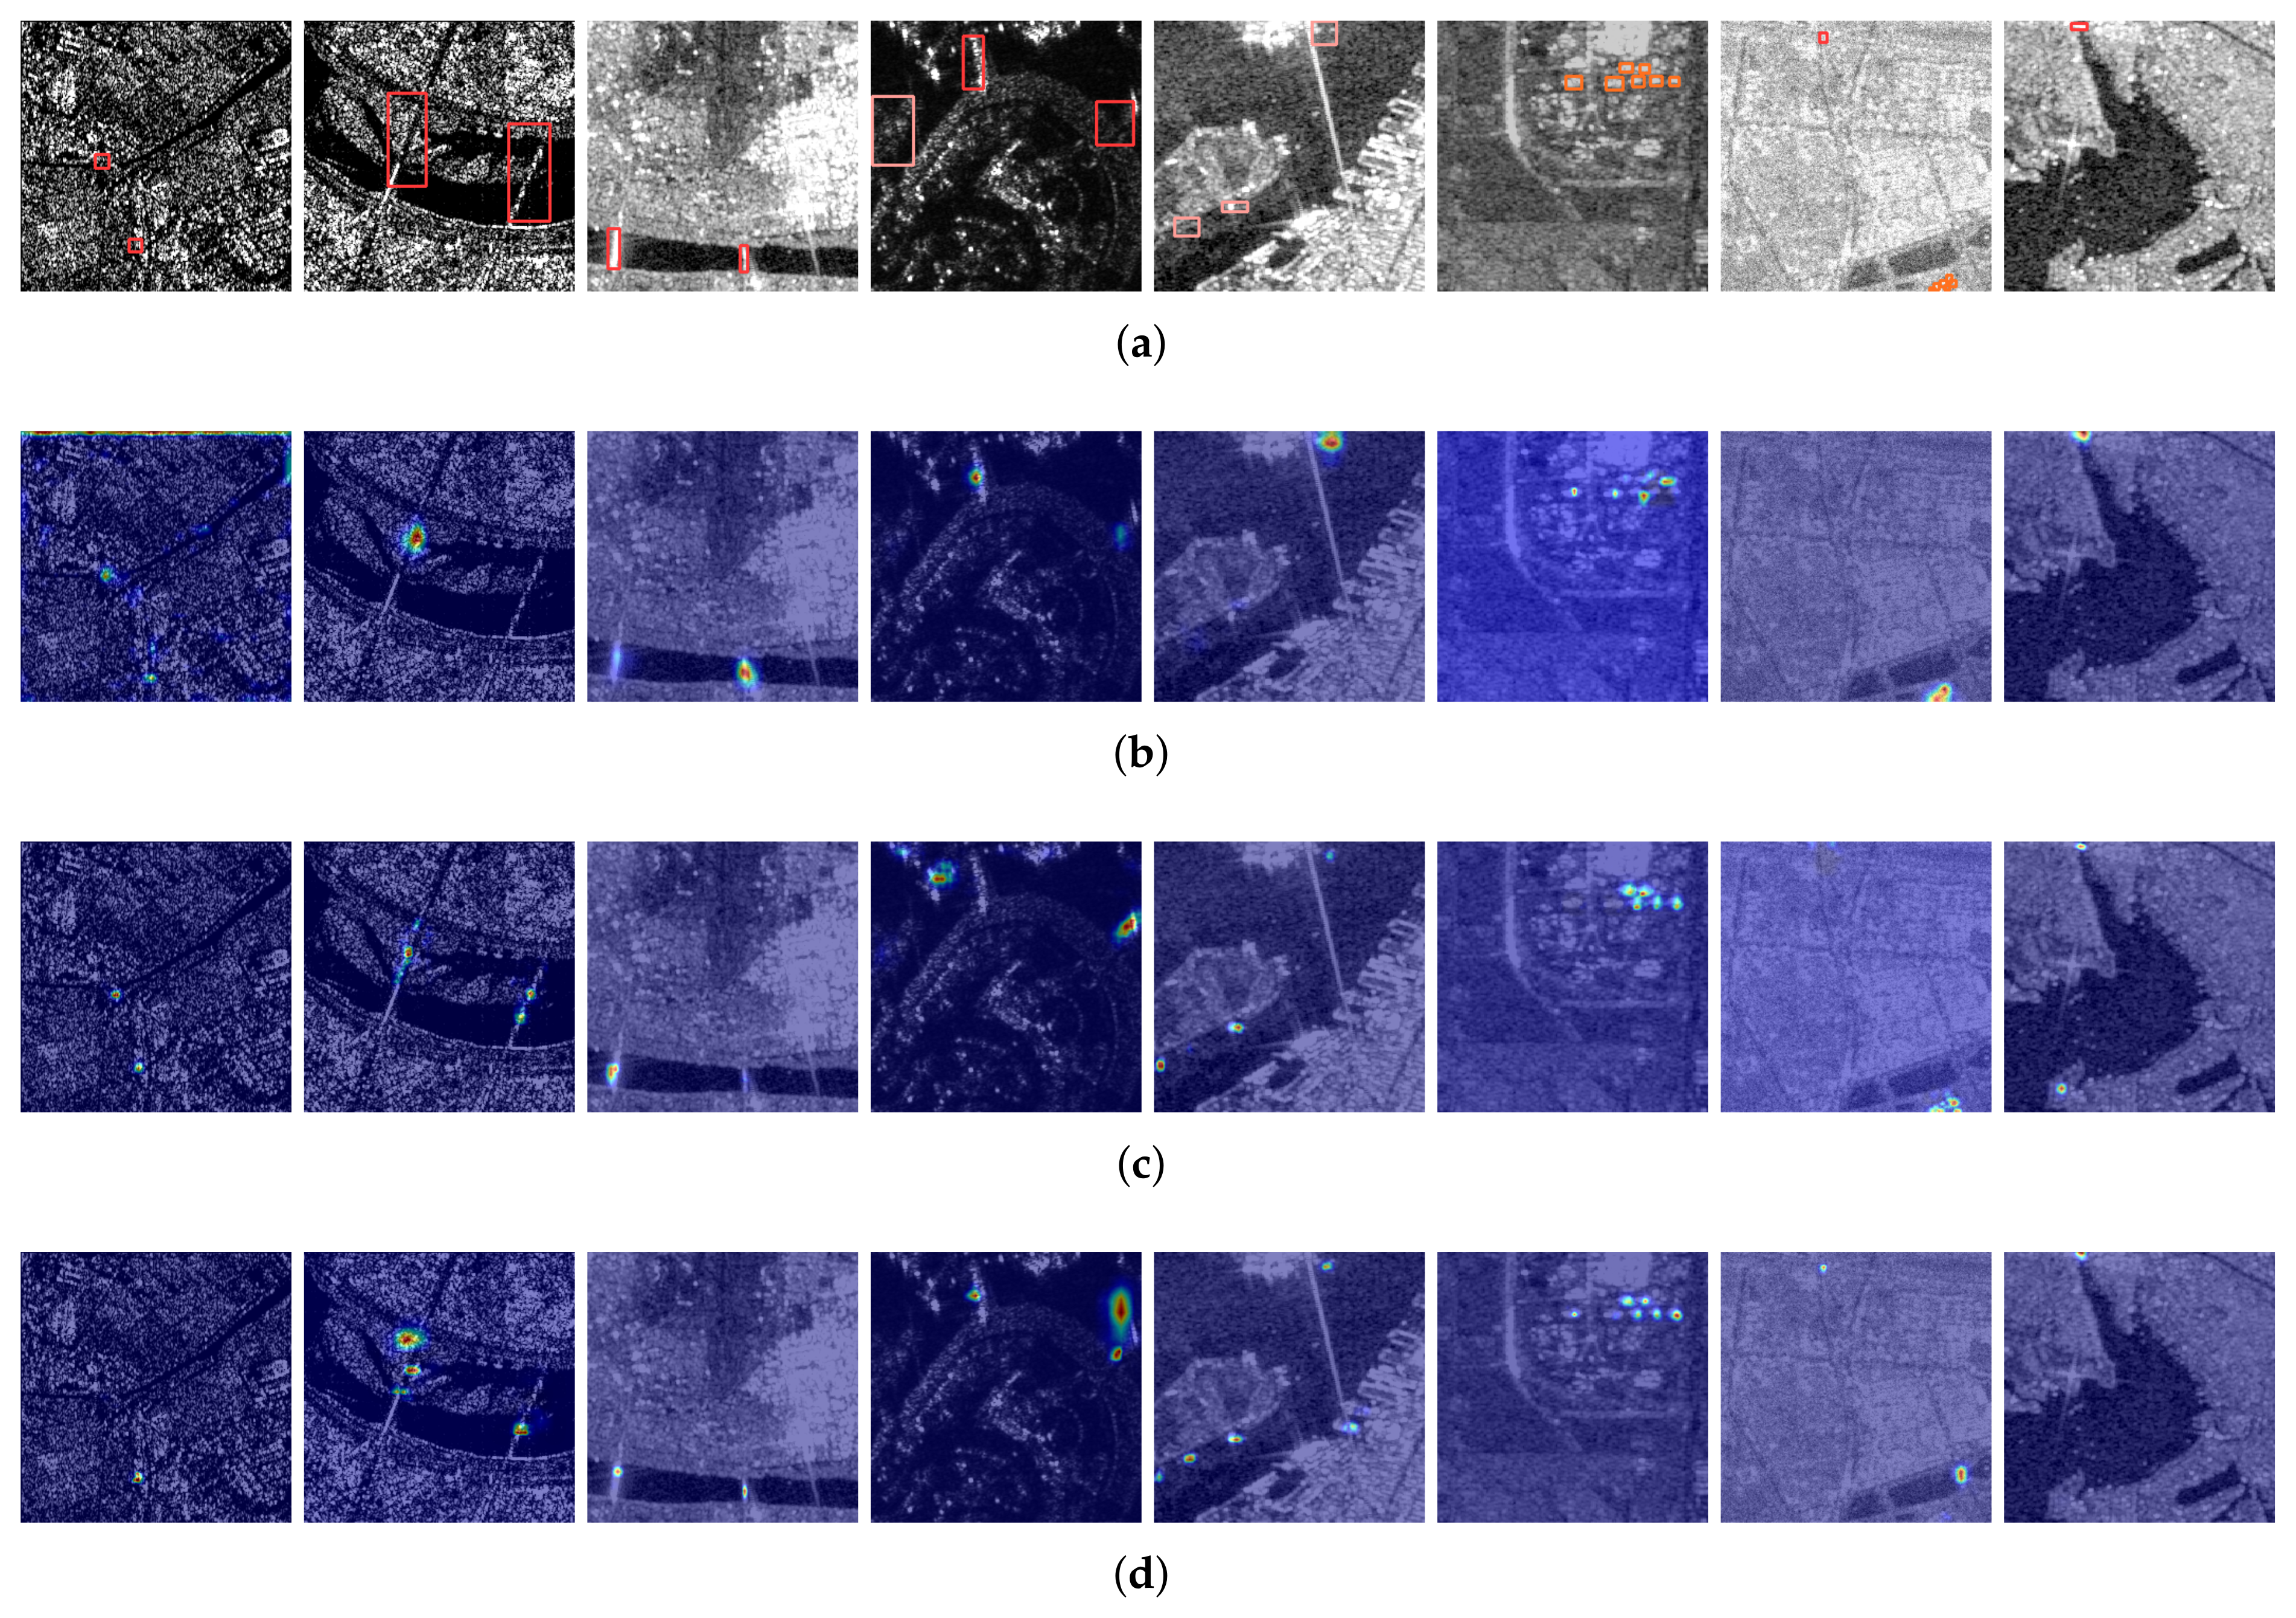
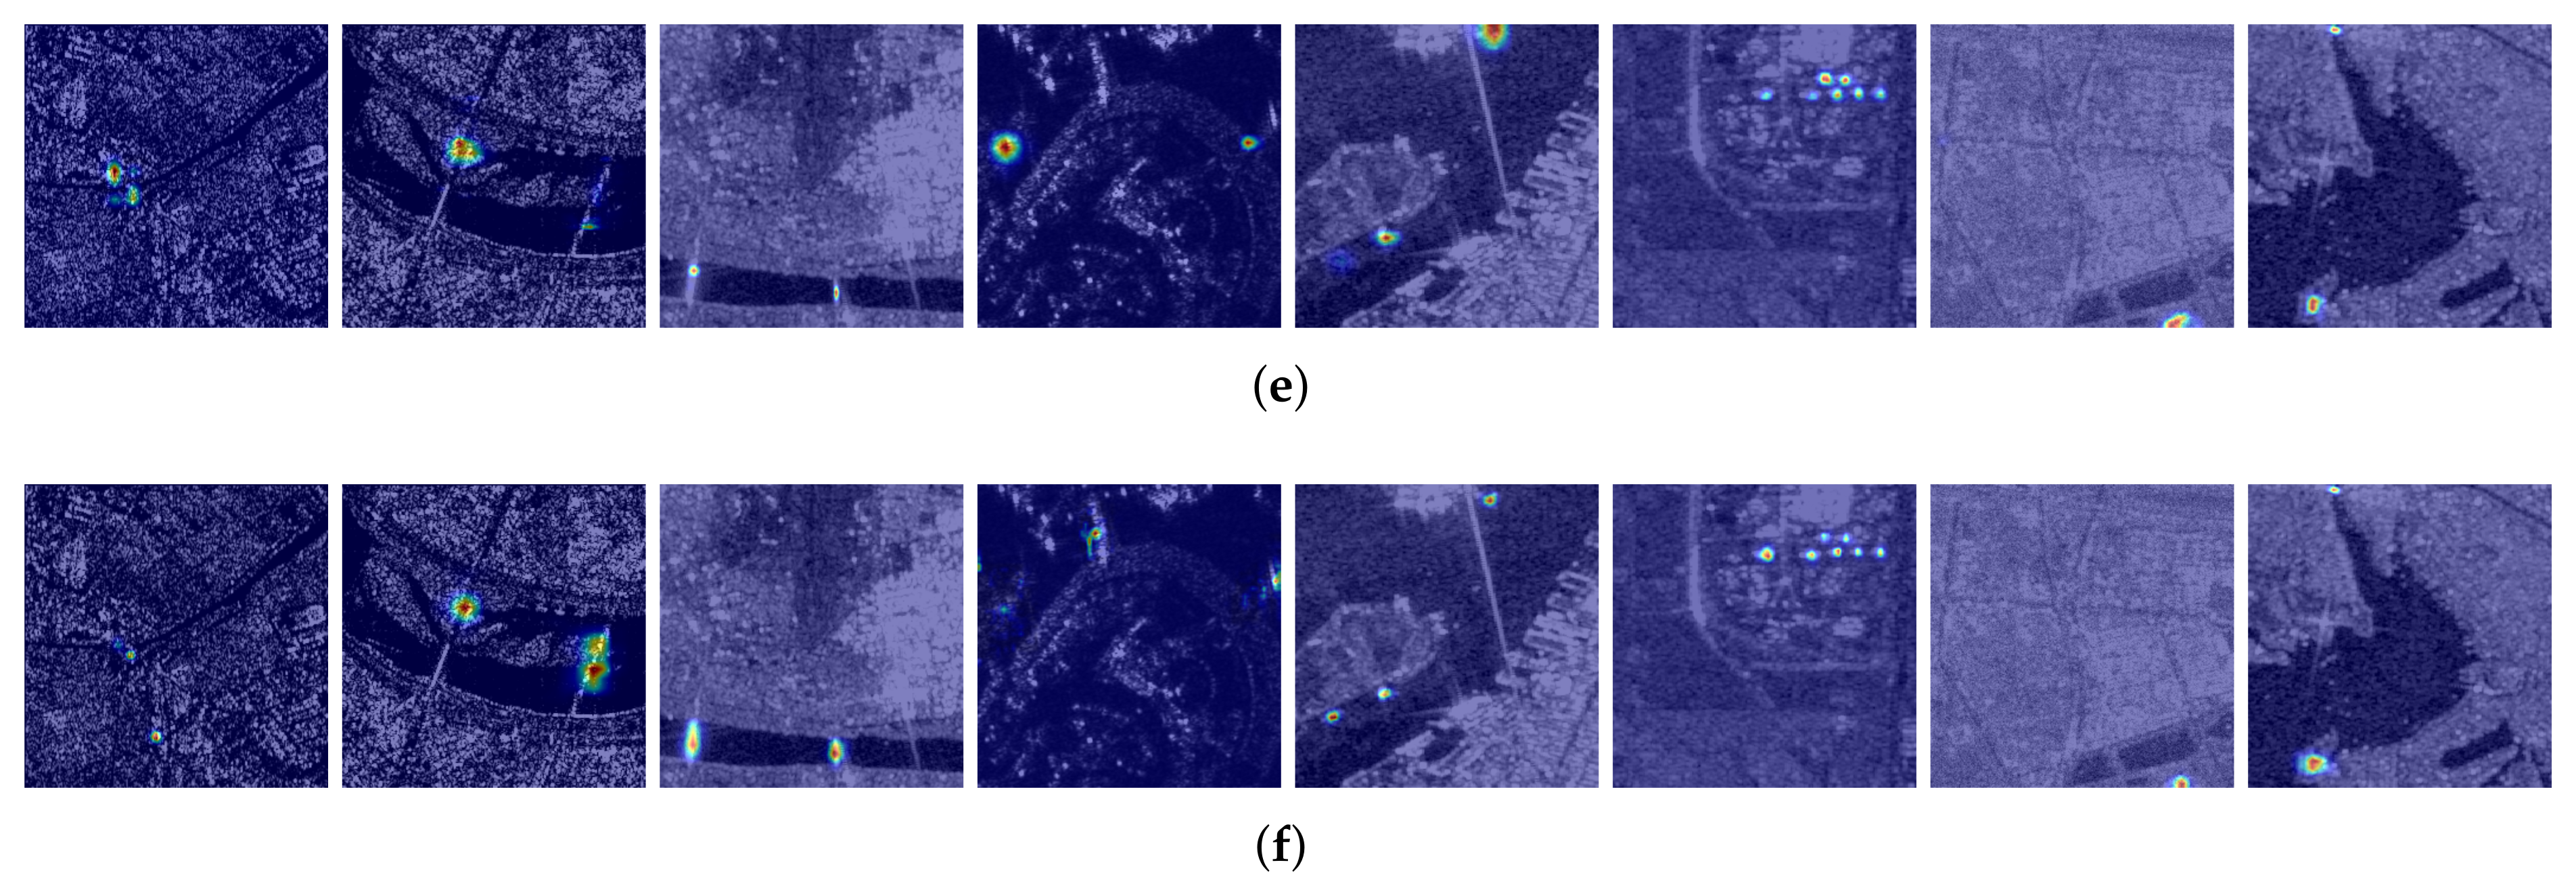
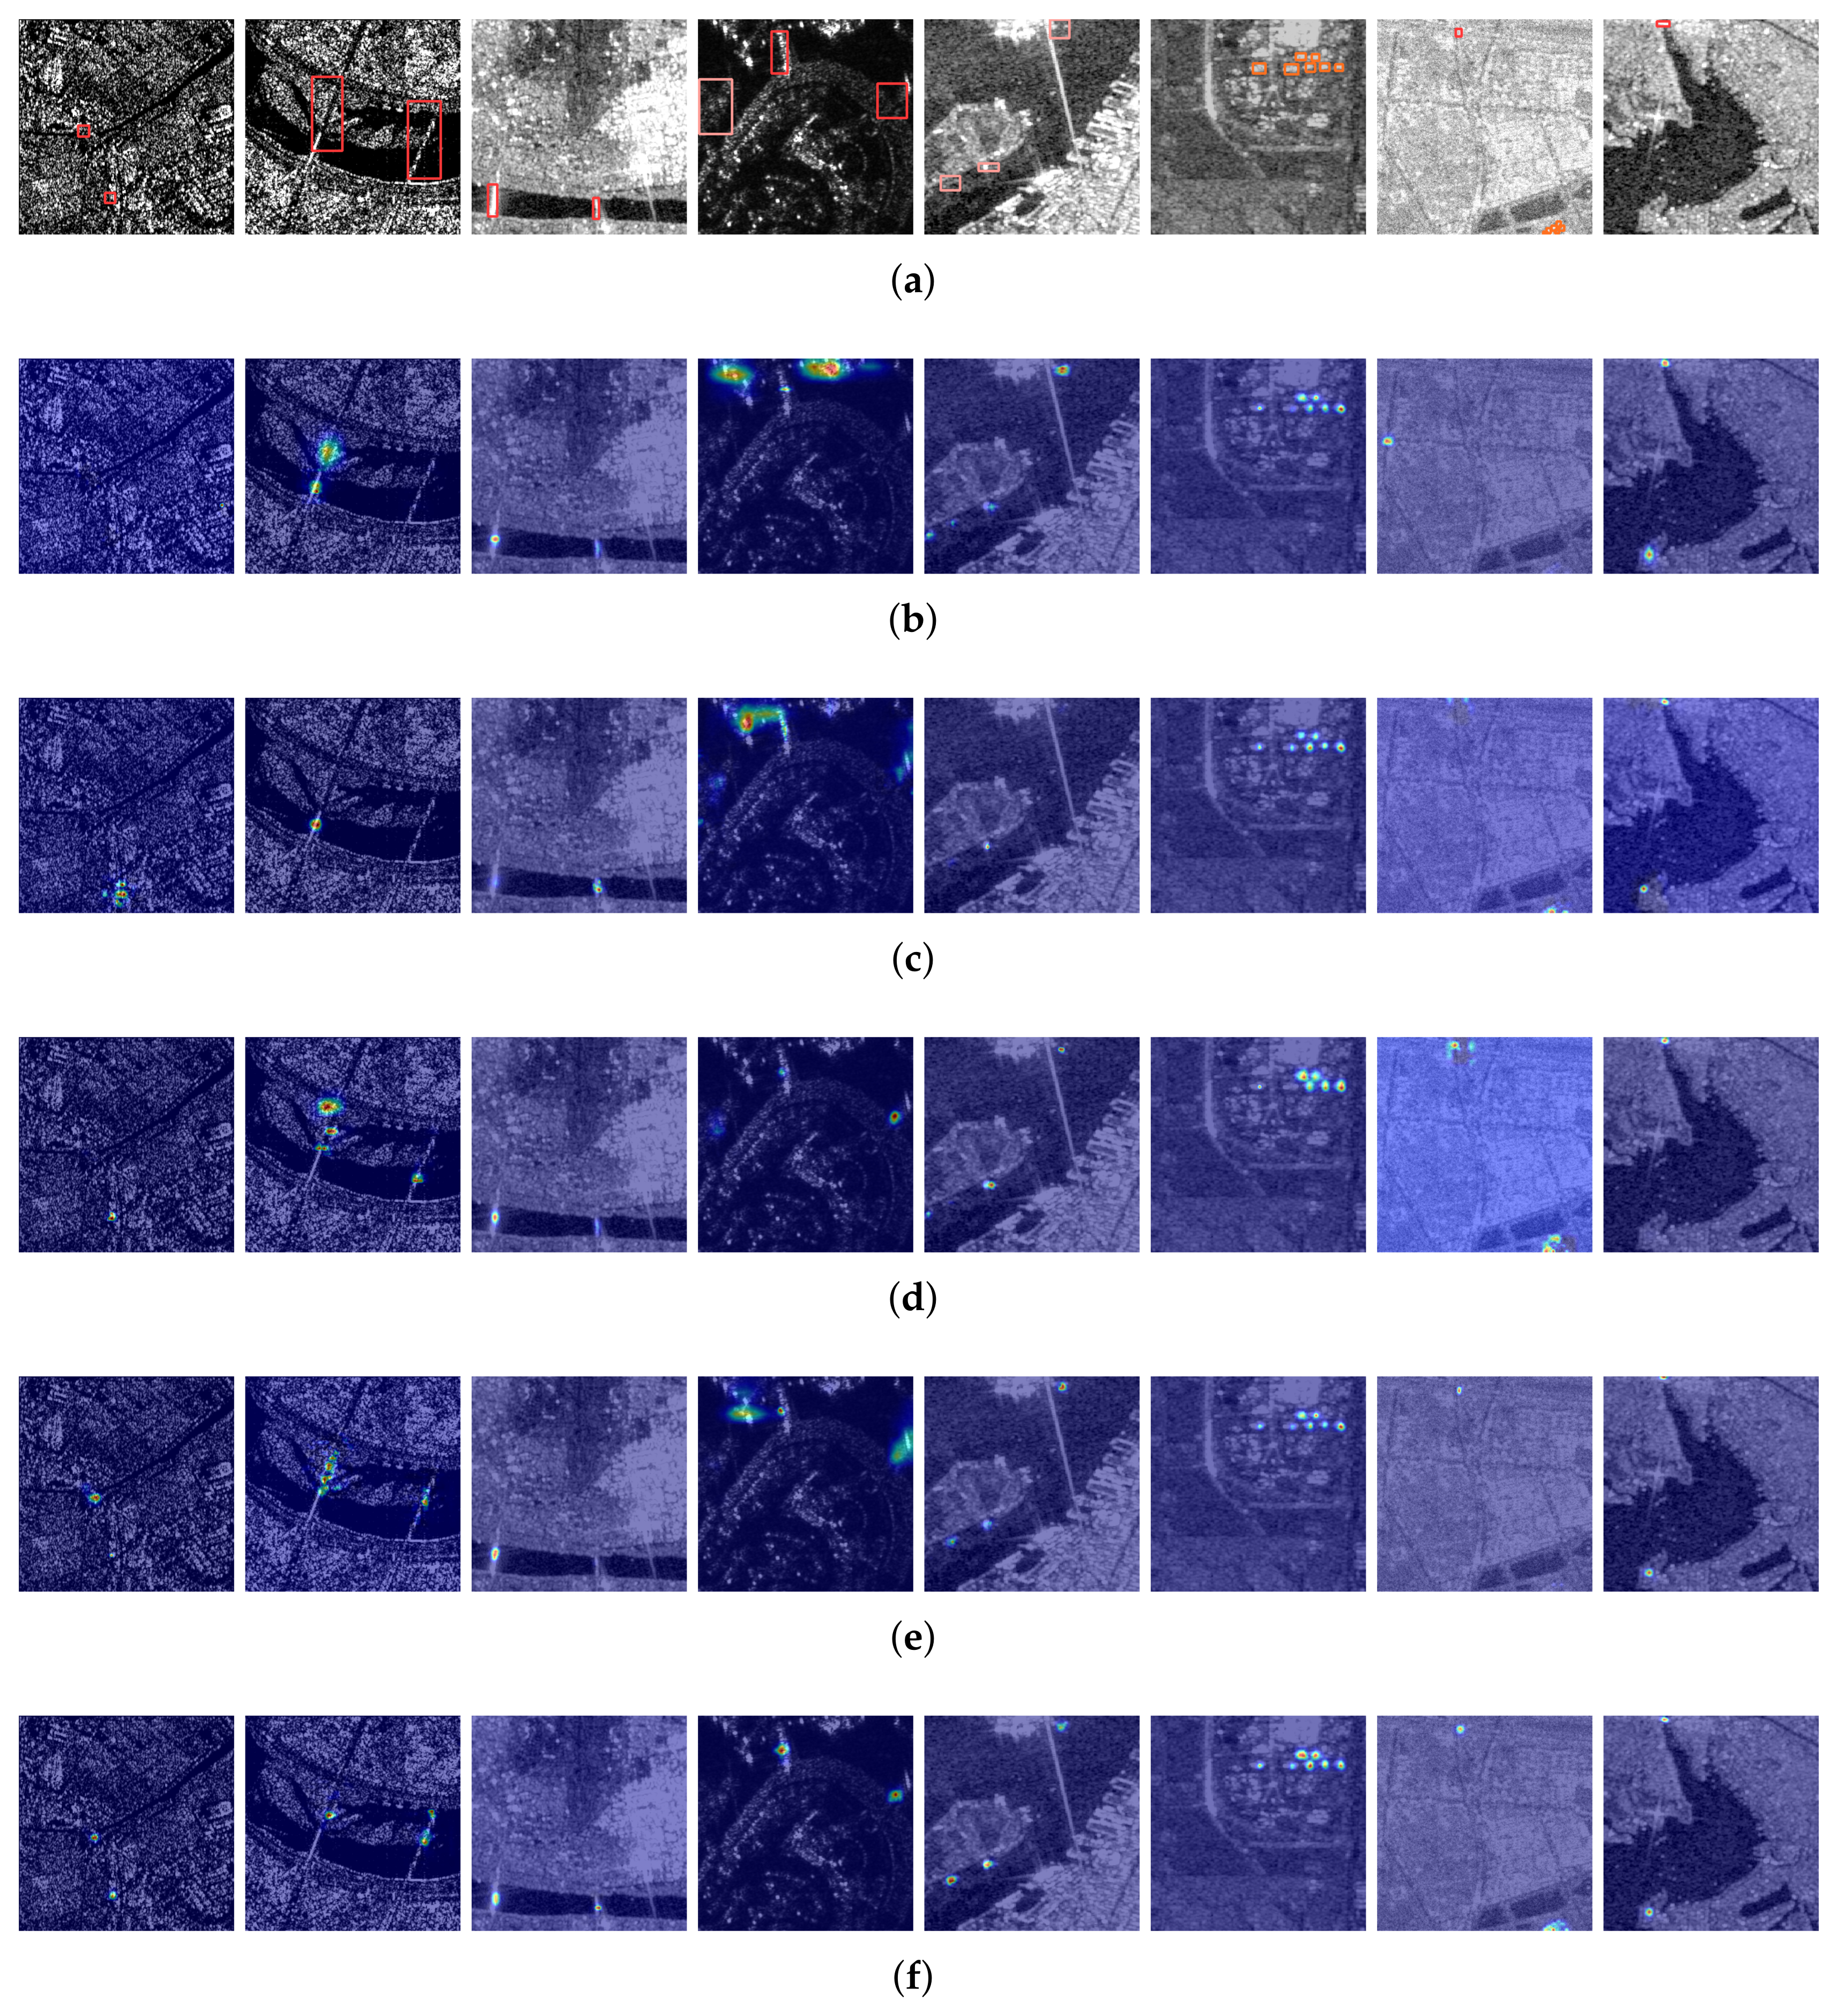
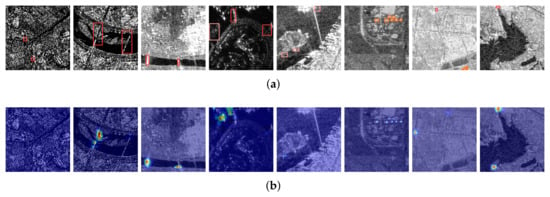
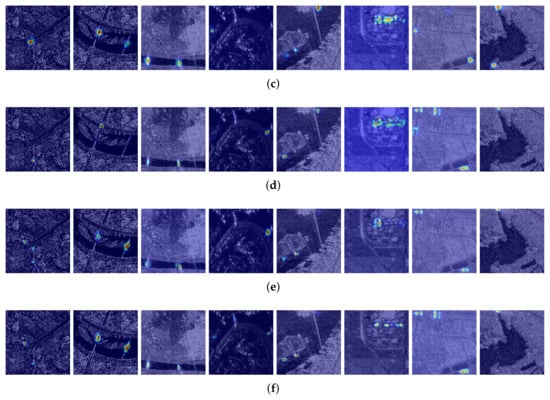
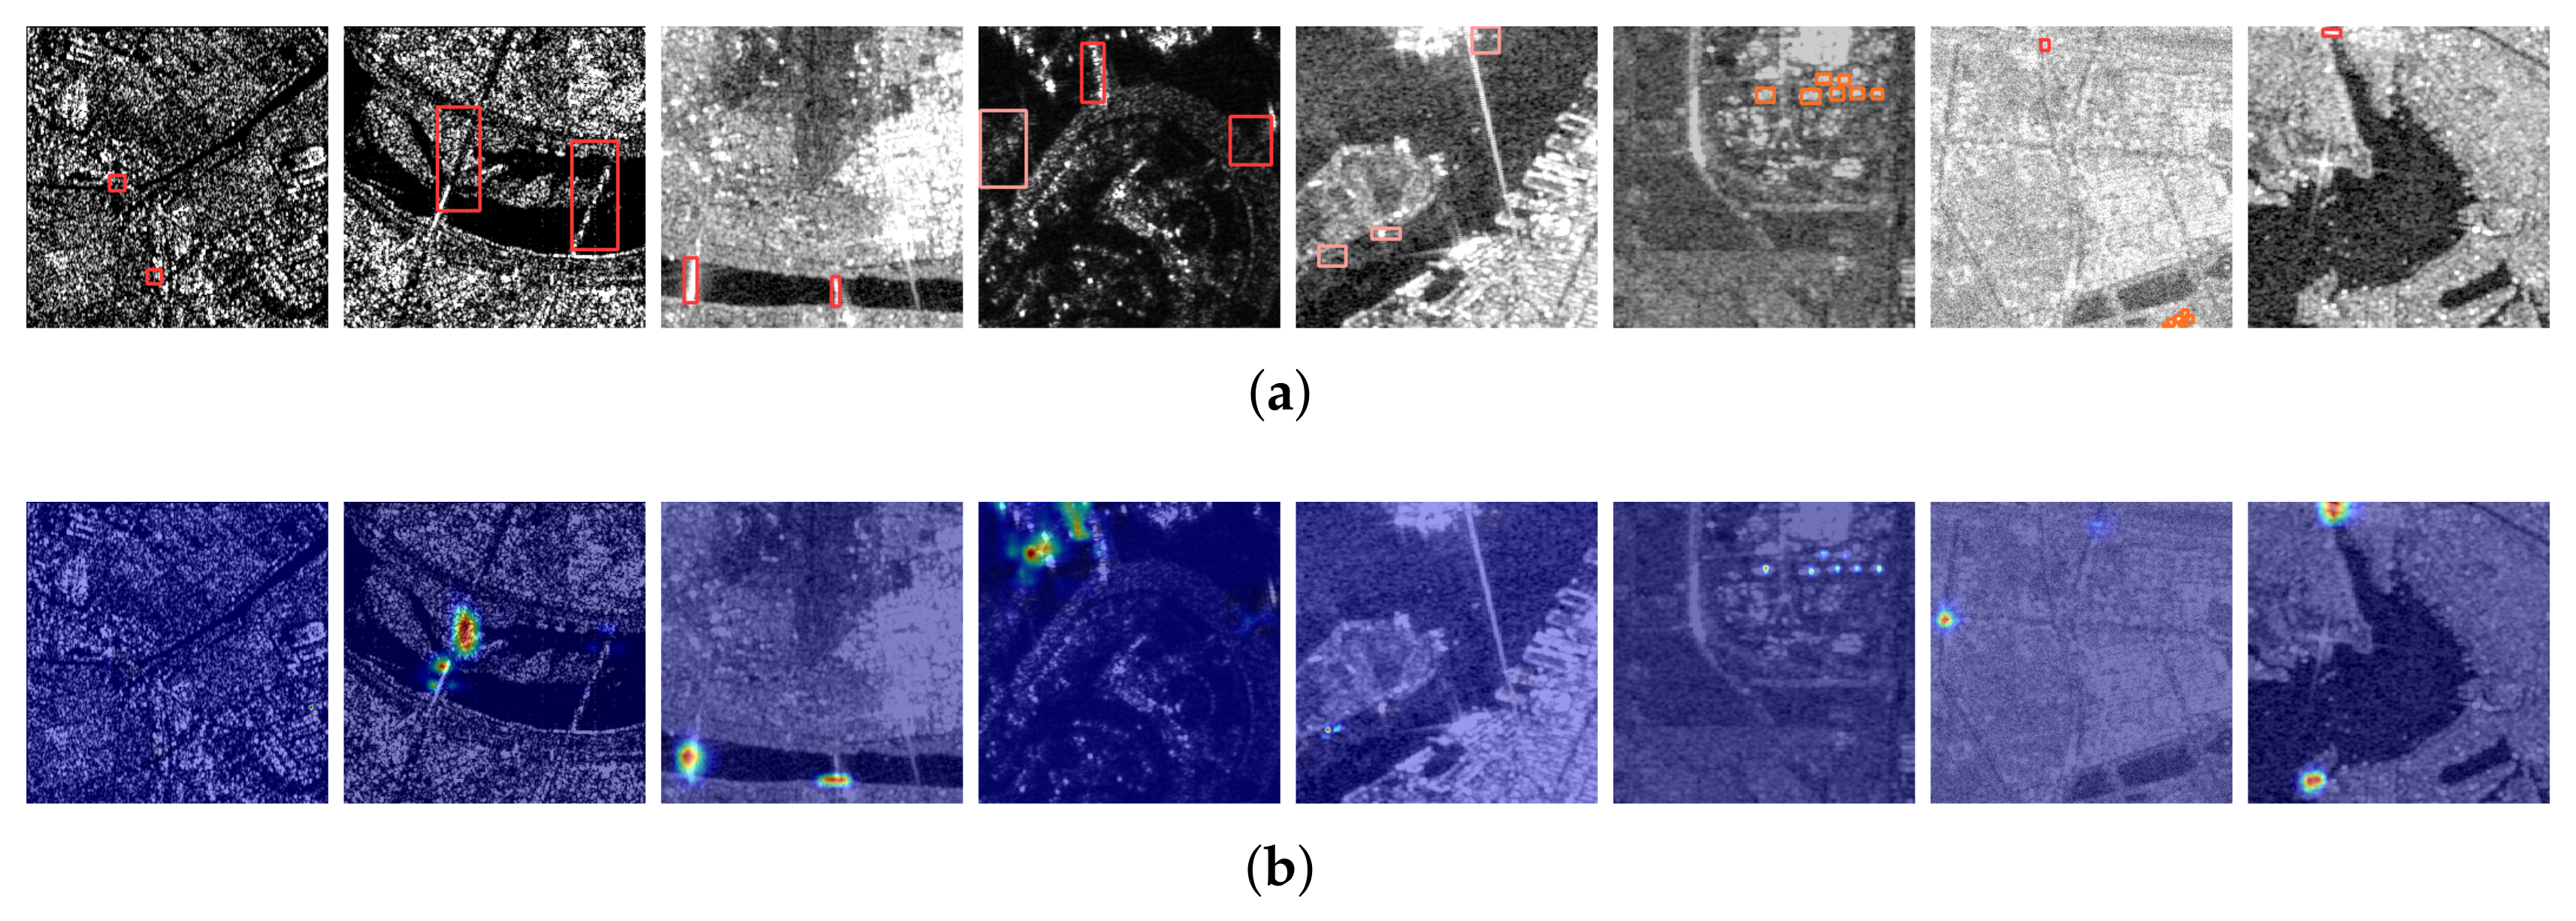
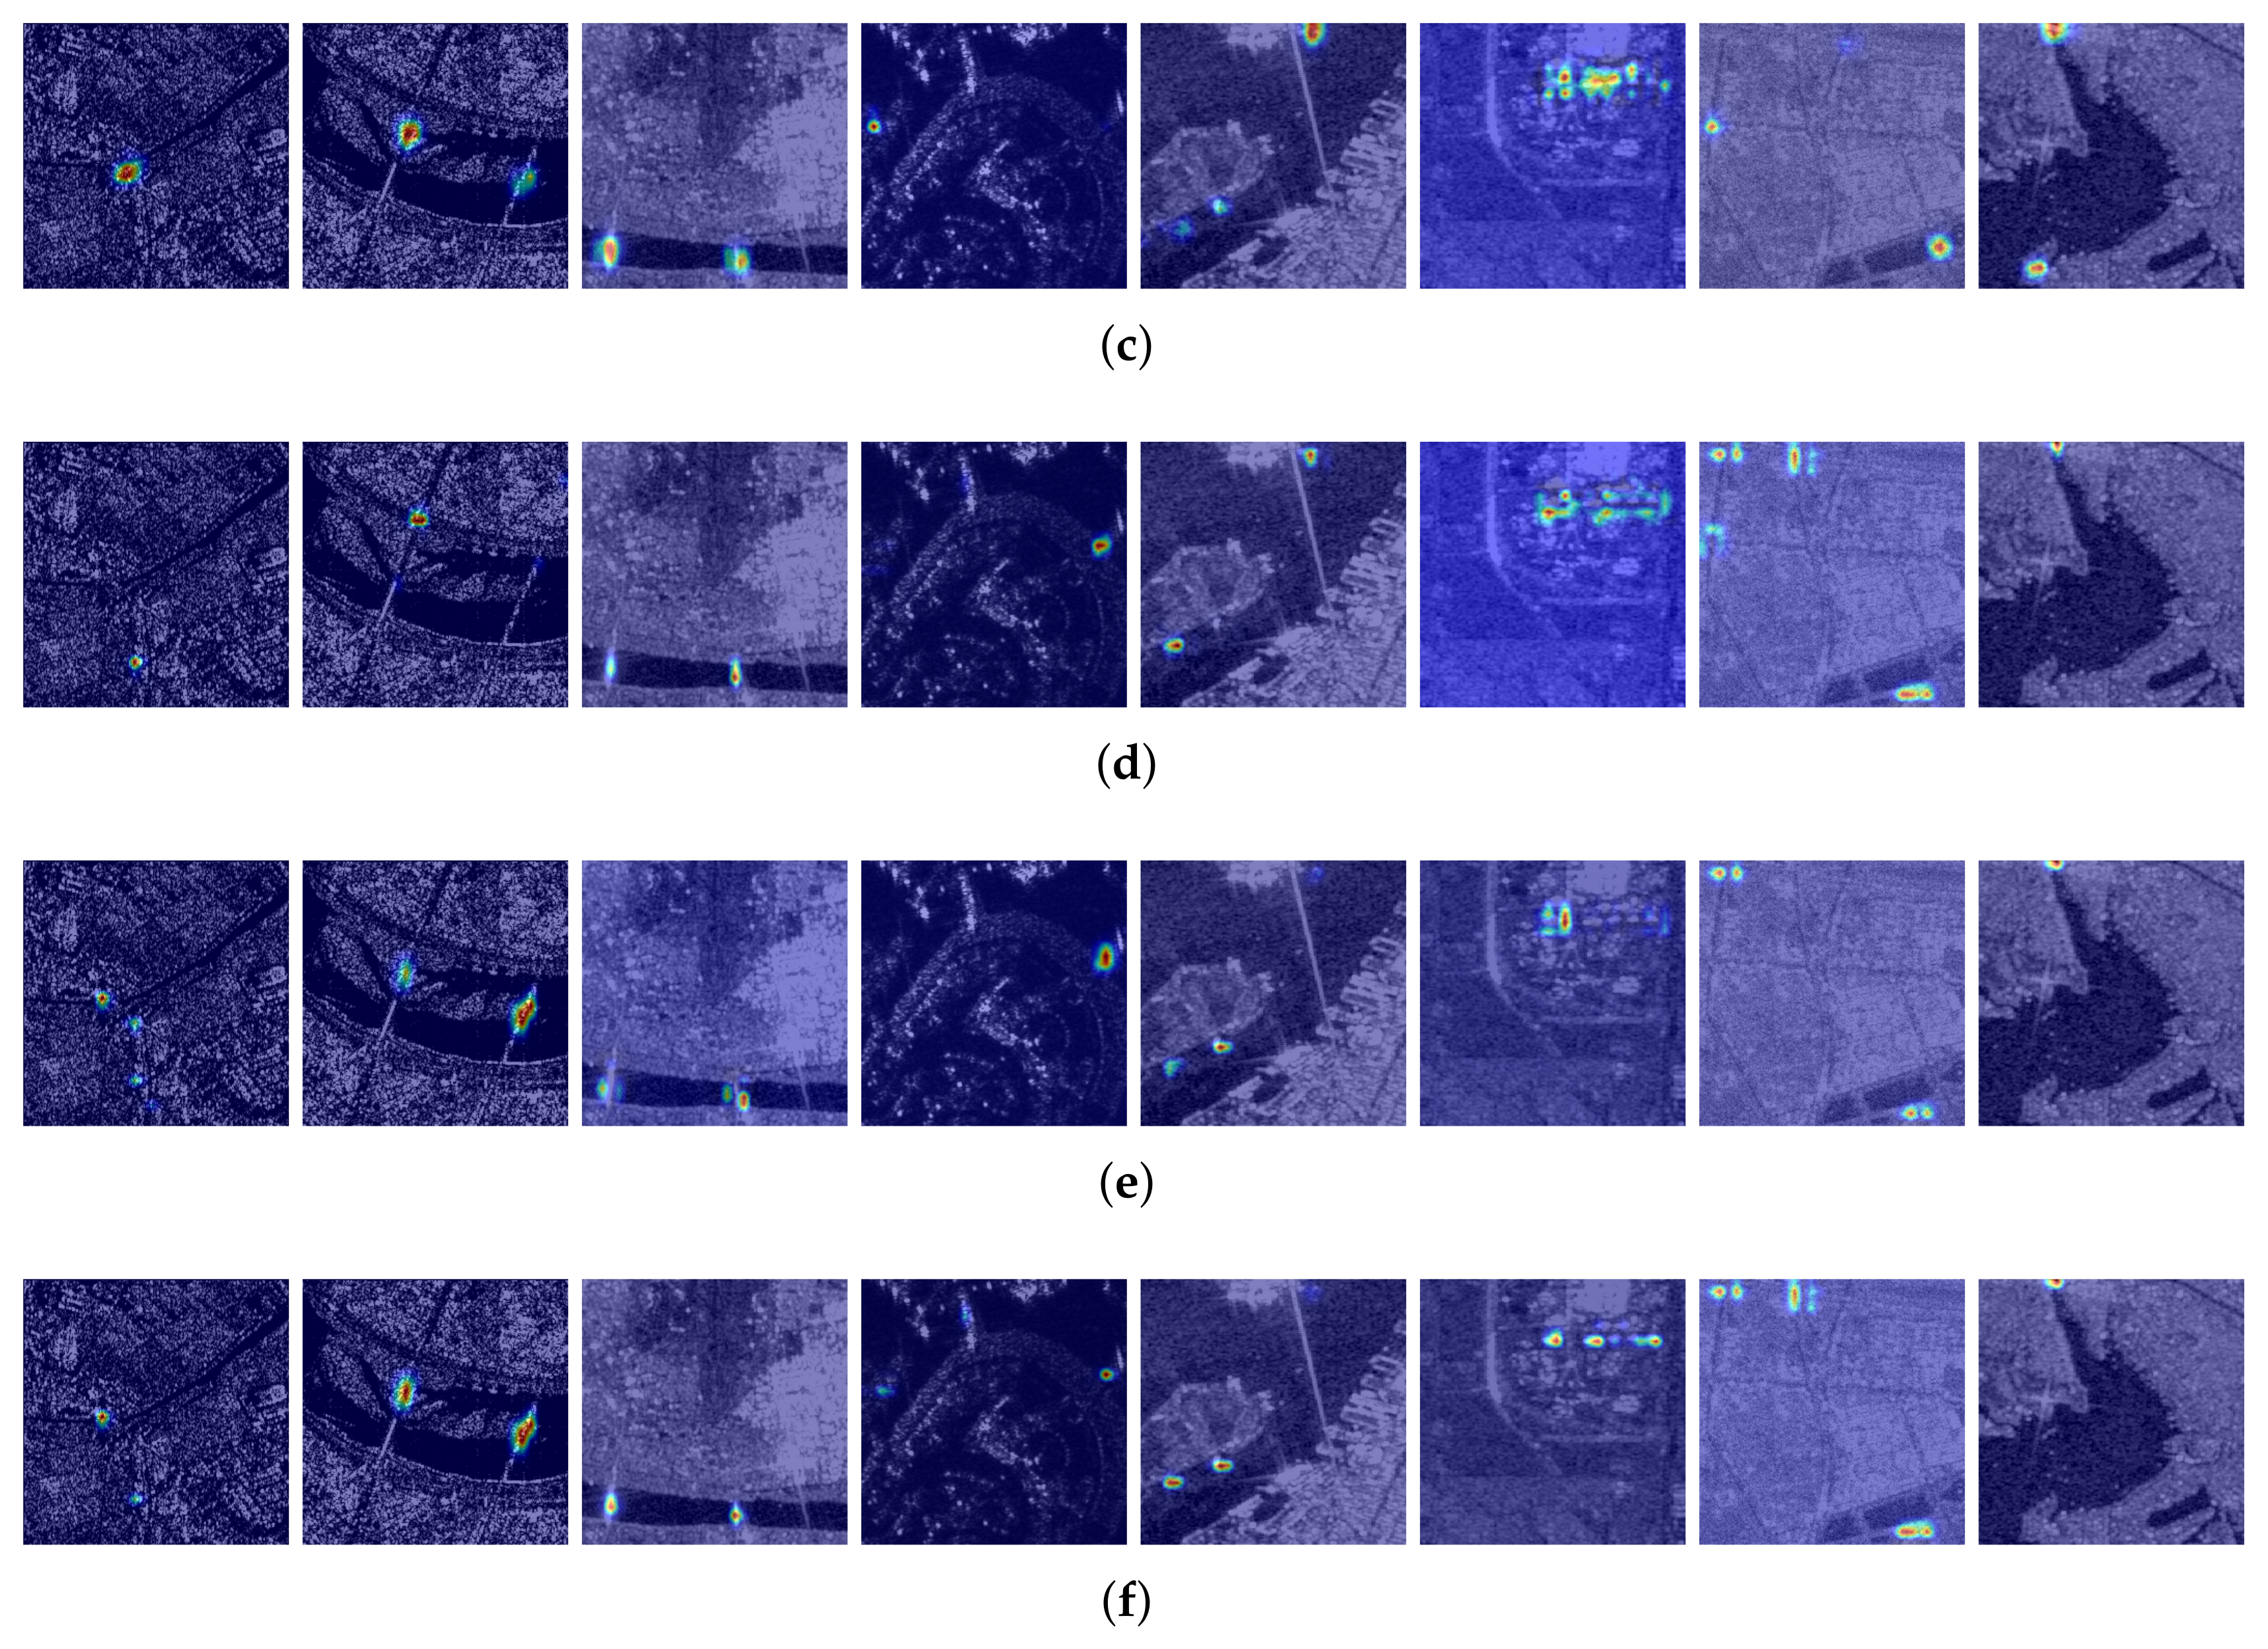
To rigorously evaluate the contributions of the MF, BSCC, and MAIE modules, we conducted controlled ablation experiments on the OGSOD-1.0 dataset, with results summarized in Table 2. All configurations were trained under identical settings (input resolution , same optimizer and schedule, identical data splits) to eliminate confounding factors, ensuring that observed changes in accuracy or efficiency stem solely from the presence or absence of individual modules. The baseline YOLOv11m model (without any proposed modules) achieved an of 76.2%, corresponding to 50.1% across the three representative object categories (Bridge, Harbor, Oil Tank). Integrating the MF module alone increased by 5.3% to 81.5%, with marginal parameter growth (+0.8 M) and a slight drop in FPS (from 75.8 to 70.4), reflecting the cost of expanded receptive fields. Introducing the BSCC module alone yielded a notable gain of 12.5% (to 88.7%), particularly benefiting category-level AP for Oil Tank (from 47.5% to 75.8%), at the expense of a moderate rise in FLOPs (+6.9 G) and a small FPS reduction (75.8 to 72.5). Combining BSCC and MAIE further enhanced cross-modal interaction, raising to 90.0% (a 13.8% gain over baseline). This fusion delivers richer and more discriminative features but incurs a substantial parameter increase (to 33.0 M) and a drop in FPS to 40.3, indicating the computational overhead of multi-head attention and deformable pyramidal convolution. Employing MF, BSCC, and MAIE achieved the highest detection performance, with reaching 90.8% and at 61.0%. Bridge and Oil Tank AP values also peaked at 93.8% and 79.0%, respectively. However, this setting has the largest model footprint (34.0 M params, 27.6 G FLOPs) and the lowest FPS (38.6), underscoring the accuracy–efficiency trade-off. These results demonstrate that each proposed module brings measurable accuracy improvements: MF improves localization for small and boundary-obscured targets, BSCC significantly boosts cross-modal semantic fusion and modality-specific discrimination, and MAIE refines multi-scale feature integration. Figure 8 presents the heatmap visualization of the ablation experiment results.The combined use of all three modules maximizes accuracy, while Table 2 also provides operational metrics (parameters, FLOPs, FPS) to inform deployment decisions in resource-constrained scenarios.
Table 2.
Ablation Experiments of MF, BSCC, and MAIE on the OGSOD-1.0 dataset.
Figure 8.
EigenGradCAM heatmaps of YOLOv11m under MF, BSCC, and MAIE ablations. Module integration progressively sharpens focus on target regions and suppresses background noise, with full combination achieving the most precise and clean attention. (a) Raw images with ground truth. (b) YOLOv11m. (c) MAIENet-MF. (d) MAIENet-BSCC. (e) MAIENet-BSCC-MAIE. (f) MAIENet-MF-BSCC-MAIE.
We compared detection performance with and without the PSA module (Table 3) under identical settings. Including PSA yielded / of 90.4%/60.2%, 34.9 M parameters, 27.9 G FLOPs, and 34.7 FPS. Removing PSA improved by 0.4%, by 0.8%, and FPS by 11.5%, while reducing parameters (−0.9 M) and FLOPs (−0.3 G). The slight accuracy gain and lower computational load indicate PSA’s attention operations may be redundant, thus it was omitted after integrating MAIE.
Table 3.
Comparison results of different operations, the bold indicates the best metric.
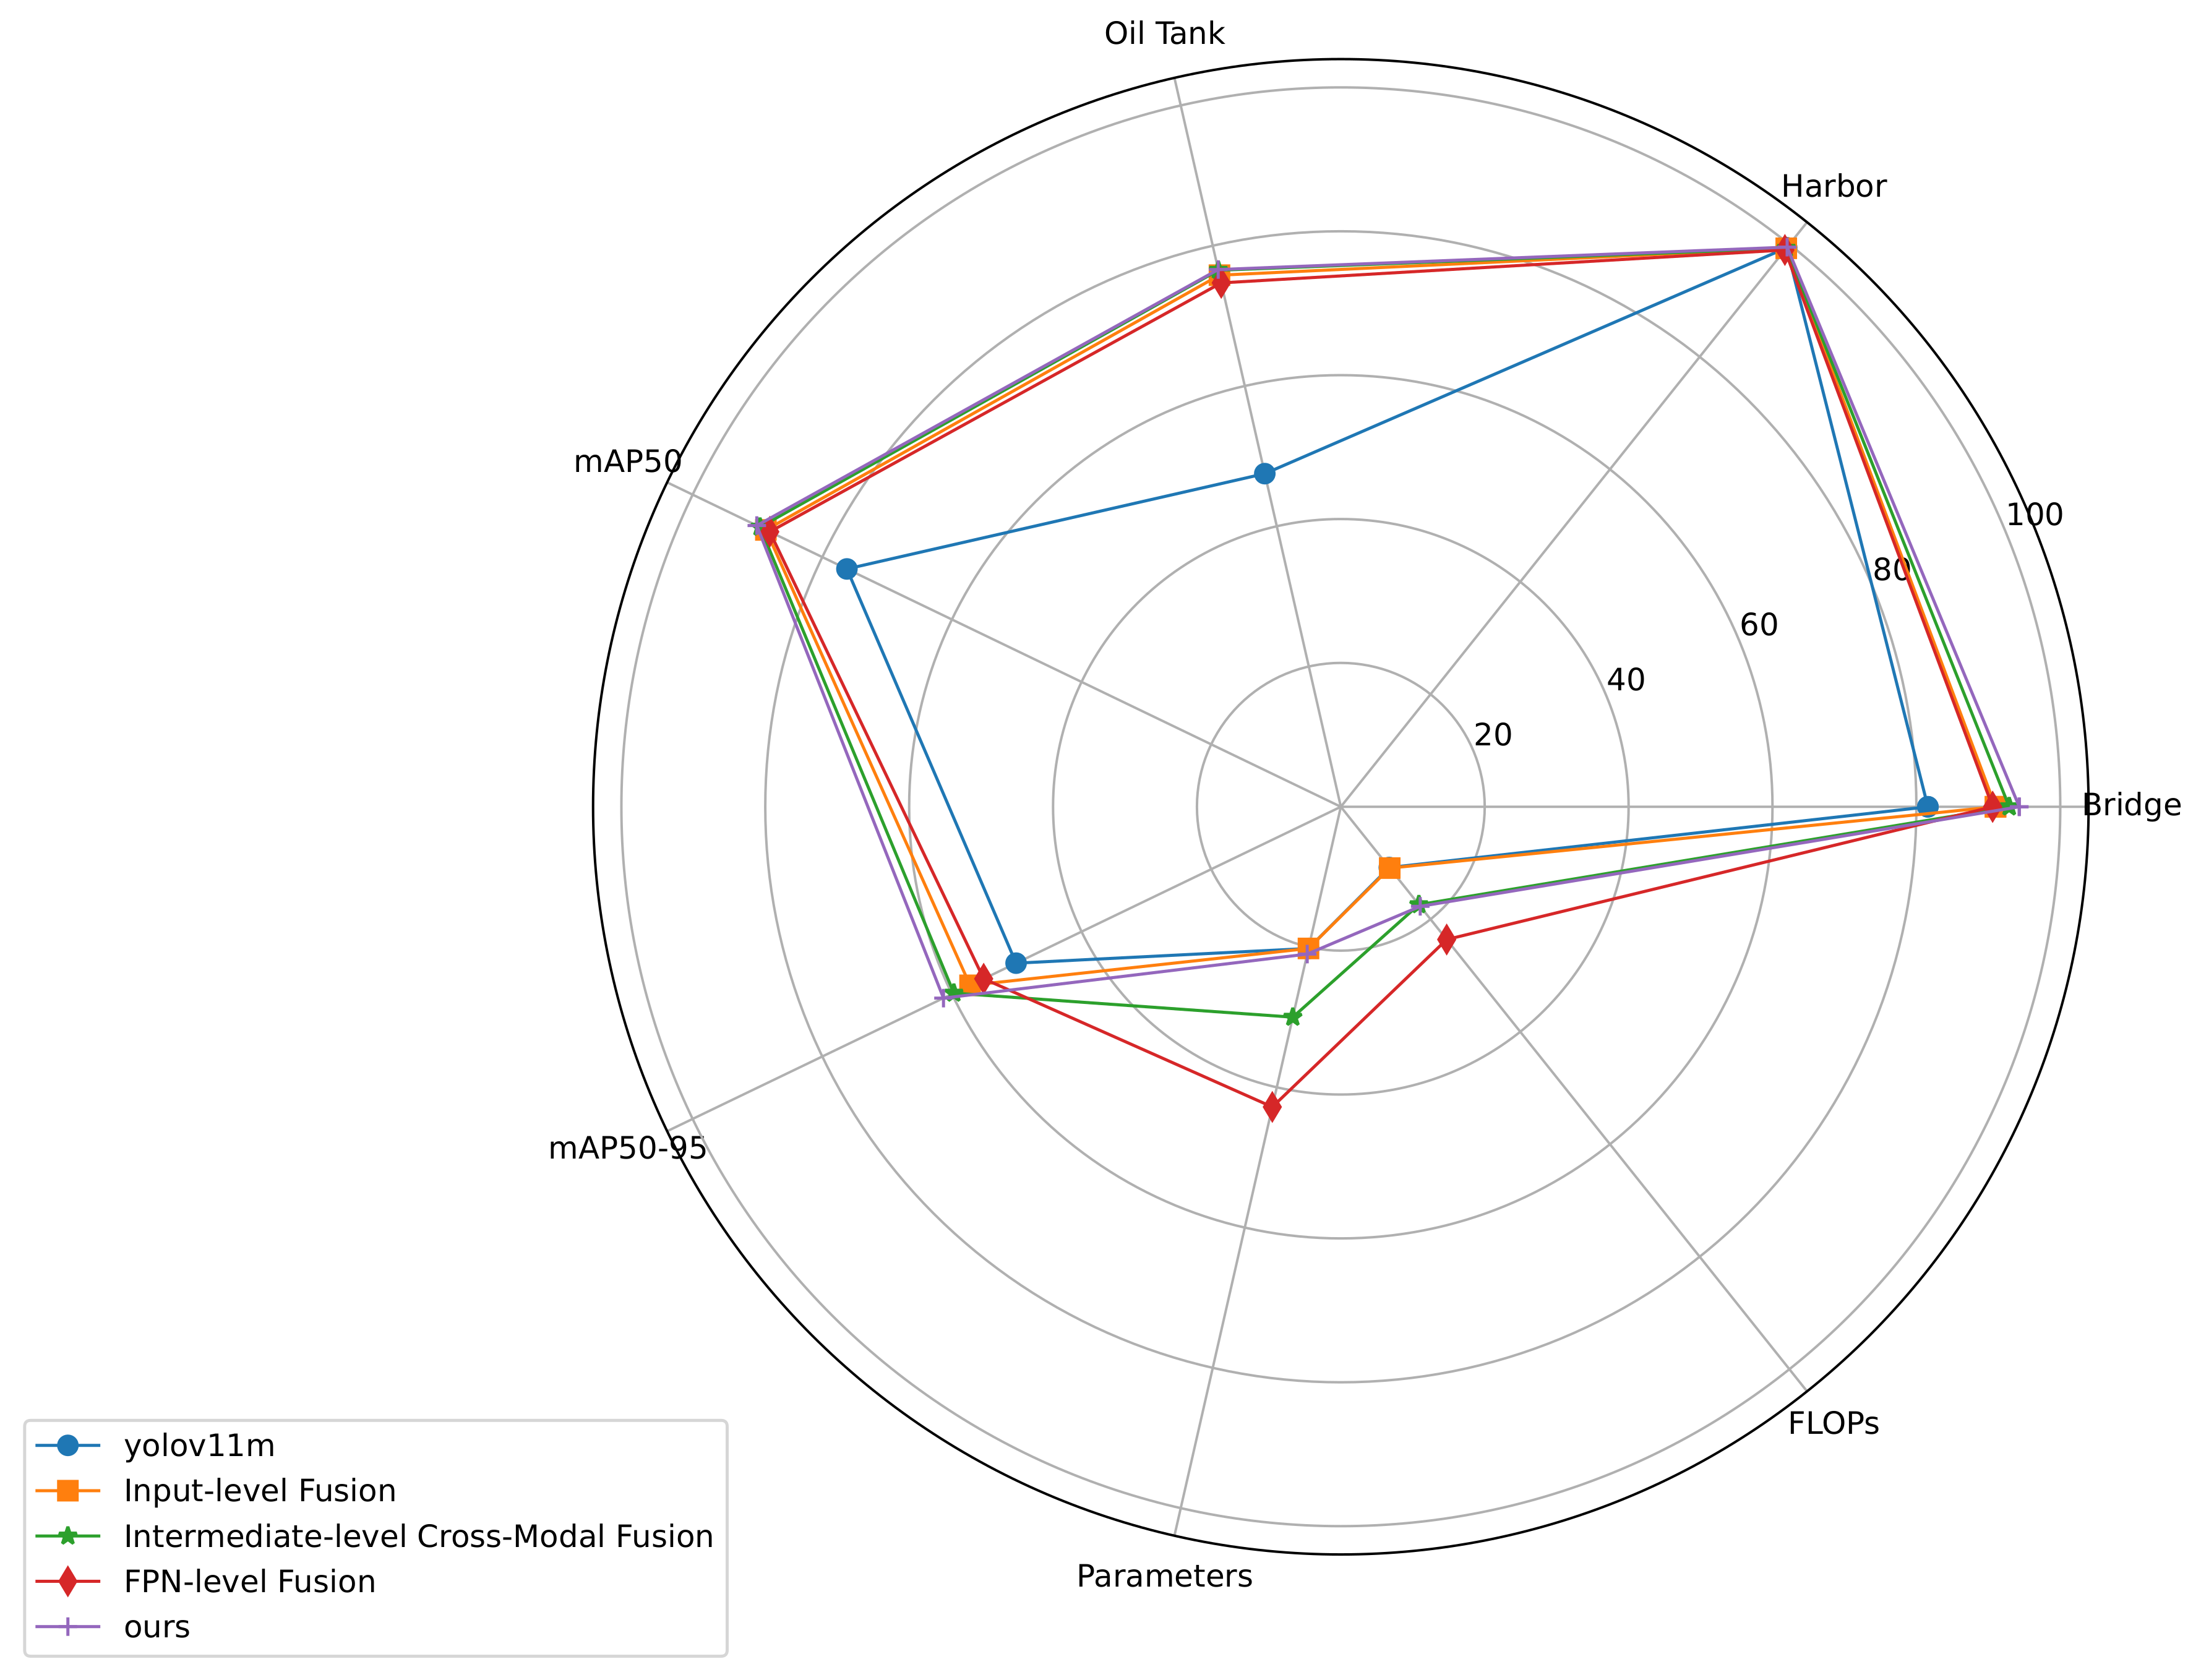
To validate the effectiveness of the proposed BSCC module, we conducted a comparison with several commonly used multimodal fusion methods. These include input-level fusion, intermediate-level cross-modal fusion, and FPN-level fusion, as illustrated in Figure 2. The results of the comparative experiment are presented in Figure 9. The comparison was conducted across seven aspects, including detection accuracy and the number of parameters. It can be observed that the proposed BSCC fusion method requires relatively fewer parameters while achieving higher object detection accuracy.
Figure 9.
Comparative analysis of different fusion methods.
To further validate the applicability of the proposed MAIE module, comparative experiments were conducted to evaluate the impact of different mounting positions on model performance (Table 4). Compared to the previous two methods, installing the MAIE module only in stage 5 resulted in a slight decrease in accuracy for oil tank and harbor, but an improvement of 0.1% and 0.7% for , respectively. Furthermore, demonstrated gains of 0.7% and 1.4% in the respective configurations. Concurrently, parameter reductions of 67.7 M (66.6%) and 80.7 M (70.3%) were achieved, while FLOPs decreased by 3.2 G (10.4%) and 4.2 G (13.2%). These results indicate that stage 5 placement optimizes object detection accuracy while minimizing model complexity.
Table 4.
Comparison results of different operations, the bold indicates the best metric.
4.3.4. Generalization Analysis
To validate the generalizability of the proposed module, we integrated it into two state-of-the-art models, YOLOv10m and YOLOv12m. The experimental results are presented in Table 5, with intermediate feature maps shown in Figure 10 and Figure 11. As indicated in Table 5, incorporating the proposed module into the YOLOv10m model led to improvements of 17.3% and 13.1% in and , respectively. Similarly, for the YOLOv12m network, the introduction of the proposed module resulted in performance gains of 20.8% in and 16.5% in . These results demonstrate that the proposed module exhibits strong generalization performance across different network architectures.
Table 5.
Ablation Study Results with YOLOv10 and YOLOv12.
Figure 10.
EigenGradCAM heatmaps of YOLOv10m under MF, BSCC, and MAIE ablations. (a) Raw images with ground truth. (b) YOLOv10m. (c) YOLOv10m-MF. (d) YOLOv10m-BSCC. (e) YOLOv10m-BSCC-MAIE. (f) YOLOv10m-MF-BSCC-MAIE.
Figure 11.
EigenGradCAM heatmaps of YOLOv12m under MF, BSCC, and MAIE ablations. (a) Raw images with ground truth. (b) YOLOv12m. (c) YOLOv12m-MF. (d) YOLOv12m-BSCC. (e) YOLOv12m-BSCC-MAIE. (f) YOLOv12m-MF-BSCC-MAIE.
5. Discussion
Experiments indicate that MAIENet consistently outperforms both single-modal and existing multimodal detectors. Against CoDeSAR, detection metrics improve by 3.4% () and 4.2% (), while parameters drop by 25.9%, reflecting the efficiency of SAR-optical joint feature learning. Compared with advanced multimodal baselines such as DEYOLO and CoLD, MAIENet gains 1.1–3.2% in and 1.5–4.3% in , with substantial reductions in model size, supporting deployment on satellites and edge devices.
These results are obtained under the spatial-temporal coverage, category distribution, and acquisition conditions of the OGSOD-1.0 dataset. The generalization of the method beyond this data scope remains to be verified with alternative regions, time phases, and object sets. Moreover, as MAIENet relies on paired SAR-optical inputs, scenarios lacking optical imagery may reduce its applicability, particularly for dynamic tasks where the independence of SAR from illumination and atmospheric conditions is crucial. Visualization analyses further illustrate that the BSCC, MAIE, and MF modules progressively refine attention to target regions while suppressing background noise, validating their role in addressing key challenges in multimodal detection.
6. Conclusions
We present MAIENet, a lightweight multimodal feature enhancement framework tailored for SAR object detection via optical-SAR complementarity. The BSCC module performs modality-specific feature separation and fusion, MAIE enhances deep adaptive cross-modal interactions, and MF expands receptive fields. Together, they mitigate clutter interference, limited texture detail, and low signal-to-noise challenges in SAR imagery.
Experimental results demonstrate that dynamic reweighting and directional attention in cross-modal integration can significantly improve detection accuracy while keeping computational costs under control. The overall architecture is compatible with different backbones and detection tasks, and can be extended to other modality combinations such as hyperspectral or thermal imagery. Future work will evaluate MAIENet on broader datasets, including scenarios without optical data, to further investigate its robustness and adaptability under realistic, variable observation conditions.
Author Contributions
Conceptualization, Y.T., G.C. and J.L.; methodology, Y.T.; software, Y.T. and K.X.; validation, Y.T., X.F. and K.X.; formal analysis, Y.T.; investigation, Y.T. and K.X.; resources, Y.T. and K.X.; data curation, Y.T., X.F. and K.X.; writing—original draft preparation, Y.T.; writing—review and editing, Y.T., G.C. and J.L.; visualization, Y.T., X.F. and K.X.; supervision, G.C. and J.L.; project administration, Y.T., G.C. and J.L.; funding acquisition, J.L. All authors have read and agreed to the published version of the manuscript.
Funding
This work was supported in part by the National Natural Science Foundation of China under Grant [61701100].
Data Availability Statement
Publicly available datasets were analyzed in this paper. OGSDO-1.0 dataset can be found here: (https://github.com/mmic-lcl/Datasets-and-benchmark-code, accessed on 10 June 2025).
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Cervantes-Hernández, P.; Celis-Hernández, O.; Ahumada-Sempoal, M.A.; Reyes-Hernández, C.A.; Gómez-Ponce, M.A. Combined use of SAR images and numerical simulations to identify the source and trajectories of oil spills in coastal environments. Mar. Pollut. Bull. 2024, 199, 115981. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Zhao, B.; Sui, H.; Liu, J.; Shi, W.; Wang, W.; Xu, C.; Wang, J. Flood inundation monitoring using multi-source satellite imagery: A knowledge transfer strategy for heterogeneous image change detection. Remote Sens. Environ. 2024, 314, 114373. [Google Scholar] [CrossRef] [Scilit]
- Karvonen, J.; Gegiuc, A.; Niskanen, T.; Montonen, A.; Buus-Hinkler, J.; Rinne, E. Iceberg detection in dual-polarized c-band SAR imagery by segmentation and nonparametric CFAR (SnP-CFAR). IEEE Trans. Geosci. Remote Sens. 2022, 60, 1–12. [Google Scholar] [CrossRef] [Scilit]
- Zhang, L.; Liu, C. A novel saliency-driven oil tank detection method for synthetic aperture radar images. In Proceedings of the ICASSP 2020-2020 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), Barcelona, Spain, 4–8 May 2020; pp. 2608–2612. [Google Scholar] [CrossRef] [Scilit]
- Jocher, G.; Stoken, A.; Borovec, J.; Changyu, L.; Hogan, A.; Diaconu, L.; Poznanski, J.; Yu, L.; Rai, P.; Ferriday, R.; et al. Ultralytics/yolov5: v3. 0. Zenodo YOLO-V5. 2020. Available online: https://zenodo.org/records/3983579 (accessed on 13 August 2020).
- Li, C.; Li, L.; Jiang, H.; Weng, K.; Geng, Y.; Li, L.; Ke, Z.; Li, Q.; Cheng, M.; Nie, W.; et al. YOLOv6: A single-stage object detection framework for industrial applications. arXiv 2022, arXiv:2209.02976. [Google Scholar] [CrossRef] [Scilit]
- Wang, C.Y.; Bochkovskiy, A.; Liao, H.Y.M. YOLOv7: Trainable bag-of-freebies sets new state-of-the-art for real-time object detectors. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Vancouver, BC, Canada, 17–24 June 2023; pp. 7464–7475. [Google Scholar]
- Tao, S.; Shengqi, Y.; Haiying, L.; Jason, G.; Lixia, D.; Lida, L. MIS-YOLOv8: An improved algorithm for detecting small objects in UAV aerial photography based on YOLOv8. IEEE Trans. Instrum. Meas. 2025, 74, 1–12. [Google Scholar] [CrossRef] [Scilit]
- Wang, C.Y.; Yeh, I.H.; Mark Liao, H.Y. Yolov9: Learning what you want to learn using programmable gradient information. In Proceedings of the European Conference on Computer Vision, Milan, Italy, 29 September–4 October 2024; Springer: Cham, Switzerland, 2024; pp. 1–21. [Google Scholar]
- Wang, A.; Chen, H.; Liu, L.; Chen, K.; Lin, Z.; Han, J. Yolov10: Real-time end-to-end object detection. Adv. Neural Inf. Process. Syst. 2024, 37, 107984–108011. [Google Scholar]
- Khanam, R.; Hussain, M. Yolov11: An overview of the key architectural enhancements. arXiv 2024, arXiv:2410.17725. [Google Scholar] [CrossRef] [Scilit]
- Tian, Y.; Ye, Q.; Doermann, D. Yolov12: Attention-centric real-time object detectors. arXiv 2025, arXiv:2502.12524. [Google Scholar]
- Chen, Z.; Liu, C.; Filaretov, V.F.; Yukhimets, D.A. Multi-Scale ship detection algorithm based on YOLOv7 for complex scene SAR images. Remote Sens. 2023, 15, 2071. [Google Scholar] [CrossRef] [Scilit]
- Li, Z.; Ma, H.; Guo, Z. MAEE-Net: SAR ship target detection network based on multi-input attention and edge feature enhancement. Digit. Signal Process. 2025, 156, 104810. [Google Scholar] [CrossRef] [Scilit]
- Guo, Y.; Chen, S.; Zhan, R.; Wang, W.; Zhang, J. Deformable feature fusion and accurate anchors prediction for lightweight SAR ship detector based on dynamic hierarchical model pruning. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2025, 18, 15019–15036. [Google Scholar] [CrossRef] [Scilit]
- Jeong, S.; Kim, Y.; Kim, S.; Sohn, K. Enriching SAR ship detection via multistage domain alignment. IEEE Geosci. Remote Sens. Lett. 2022, 19, 1–5. [Google Scholar] [CrossRef] [Scilit]
- Zhang, R.; Guo, H.; Xu, F.; Yang, W.; Yu, H.; Zhang, H.; Xia, G.S. Optical-enhanced oil tank detection in high-resolution SAR images. IEEE Trans. Geosci. Remote Sens. 2022, 60, 1–12. [Google Scholar] [CrossRef] [Scilit]
- Shi, Y.; Du, L.; Guo, Y.; Du, Y. Unsupervised domain adaptation based on progressive transfer for ship detection: From optical to SAR images. IEEE Trans. Geosci. Remote Sens. 2022, 60, 1–17. [Google Scholar] [CrossRef] [Scilit]
- Wang, C.; Ruan, R.; Zhao, Z.; Li, C.; Tang, J. Category-oriented localization distillation for sar object detection and a unified benchmark. IEEE Trans. Geosci. Remote Sens. 2023, 61, 1–14. [Google Scholar] [CrossRef] [Scilit]
- Chen, J.; Xu, X.; Zhang, J.; Xu, G.; Zhu, Y.; Liang, B.; Yang, D. Ship target detection algorithm based on decision-level fusion of visible and SAR images. IEEE J. Miniaturization Air Space Syst. 2023, 4, 242–249. [Google Scholar] [CrossRef] [Scilit]
- Chen, Y.; Wang, B.; Guo, X.; Zhu, W.; He, J.; Liu, X.; Yuan, J. DEYOLO: Dual-feature-enhancement YOLO for cross-modality object detection. In Proceedings of the International Conference on Pattern Recognition, Kolkata, India, 1–5 December 2025; Springer: Cham, Switzerland, 2025; pp. 236–252. [Google Scholar]
- Shen, J.; Chen, Y.; Liu, Y.; Zuo, X.; Fan, H.; Yang, W. ICAFusion: Iterative cross-attention guided feature fusion for multispectral object detection. Pattern Recognit. 2024, 145, 109913. [Google Scholar] [CrossRef] [Scilit]
- Song, K.; Xue, X.; Wen, H.; Ji, Y.; Yan, Y.; Meng, Q. Misaligned visible-thermal object detection: A drone-based benchmark and baseline. IEEE Trans. Intell. Veh. 2024, 9, 7449–7460. [Google Scholar] [CrossRef] [Scilit]
- Cao, Y.; Bin, J.; Hamari, J.; Blasch, E.; Liu, Z. Multimodal object detection by channel switching and spatial attention. In Proceedings of the 2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW), Vancouver, BC, Canada, 17–24 June 2023; pp. 403–411. [Google Scholar] [CrossRef] [Scilit]
- Zhuo, S.; Bai, H.; Jiang, L.; Zhou, X.; Duan, X.; Ma, Y.; Zhou, Z. SCL-YOLOv11: A lightweight object detection network for low-illumination environments. IEEE Access 2025, 13, 47653–47662. [Google Scholar] [CrossRef] [Scilit]
- Zhang, S.; Chi, C.; Yao, Y.; Lei, Z.; Li, S.Z. Bridging the gap between anchor-based and anchor-free detection via adaptive training sample selection. In Proceedings of the 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 13–19 June 2020; pp. 9756–9765. [Google Scholar] [CrossRef] [Scilit]
- Zand, M.; Etemad, A.; Greenspan, M. Objectbox: From centers to boxes for anchor-free object detection. In Proceedings of the European Conference on Computer Vision, Tel Aviv, Israel, 23–27 October 2022; Springer: Cham, Switzerland, 2022; pp. 390–406. [Google Scholar]
- Yang, Z.; Liu, S.; Hu, H.; Wang, L.; Lin, S. RepPoints: Point set representation for object detection. In Proceedings of the 2019 IEEE/CVF International Conference on Computer Vision (ICCV), Seoul, Republic of Korea, 27 October 27–2 November 2019; pp. 9656–9665. [Google Scholar] [CrossRef] [Scilit]
- Sun, P.; Zhang, R.; Jiang, Y.; Kong, T.; Xu, C.; Zhan, W.; Tomizuka, M.; Li, L.; Yuan, Z.; Wang, C.; et al. Sparse R-CNN: End-to-end object detection with learnable proposals. In Proceedings of the 2021 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Nashville, TN, USA, 20–25 June 2021; pp. 14449–14458. [Google Scholar] [CrossRef] [Scilit]
- Li, W.; Yang, W.; Hou, Y.; Liu, L.; Liu, Y.; Li, X. SARATR-X: Toward building a foundation model for SAR target recognition. IEEE Trans. Image Process. 2025, 34, 869–884. [Google Scholar] [CrossRef] [Scilit]
- Zhang, B.; Han, Z.; Zhang, Y.; Li, Y. Blurry dense SAR object detection algorithm based on collaborative boundary refinement and differential feature enhancement. Int. J. Remote Sens. 2025, 46, 3207–3227. [Google Scholar] [CrossRef] [Scilit]
- Zhao, Y.; Lv, W.; Xu, S.; Wei, J.; Wang, G.; Dang, Q.; Liu, Y.; Chen, J. Detrs beat yolos on real-time object detection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Seattle, WA, USA, 16–22 June 2024; pp. 16965–16974. [Google Scholar]
- Bae, J.H.; Yeo, D.; Yim, J.; Kim, N.S.; Pyo, C.S.; Kim, J. Densely distilled flow-based knowledge transfer in teacher-student framework for image classification. IEEE Trans. Image Process. 2020, 29, 5698–5710. [Google Scholar] [CrossRef] [Scilit]
- Dai, X.; Jiang, Z.; Wu, Z.; Bao, Y.; Wang, Z.; Liu, S.; Zhou, E. General instance distillation for object detection. In Proceedings of the 2021 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Nashville, TN, USA, 20–25 June 2021; pp. 7838–7847. [Google Scholar] [CrossRef] [Scilit]
- Zhao, B.; Cui, Q.; Song, R.; Qiu, Y.; Liang, J. Decoupled knowledge distillation. In Proceedings of the 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, LA, USA, 18–24 June 2022; pp. 11943–11952. [Google Scholar] [CrossRef] [Scilit]
- Zheng, Z.; Ye, R.; Wang, P.; Ren, D.; Zuo, W.; Hou, Q.; Cheng, M.M. Localization distillation for dense object detection. In Proceedings of the 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, LA, USA, 18–24 June 2022; pp. 9397–9406. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).