Article

On Information Granulation via Data Clustering for Granular Computing-Based Pattern Recognition: A Graph Embedding Case Study

1
Department of Business and Management, LUISS University, Viale Romania 32, 00197 Rome, Italy
2
Department of Information Engineering, Electronics and Telecommunications, University of Rome ”La Sapienza”, Via Eudossiana 18, 00184 Rome, Italy
*
Author to whom correspondence should be addressed.
Algorithms 2022, 15(5), 148; https://doi.org/10.3390/a15050148
Submission received: 11 April 2022 / Revised: 23 April 2022 / Accepted: 24 April 2022 / Published: 27 April 2022
(This article belongs to the Special Issue Graph Embedding Applications)

Abstract

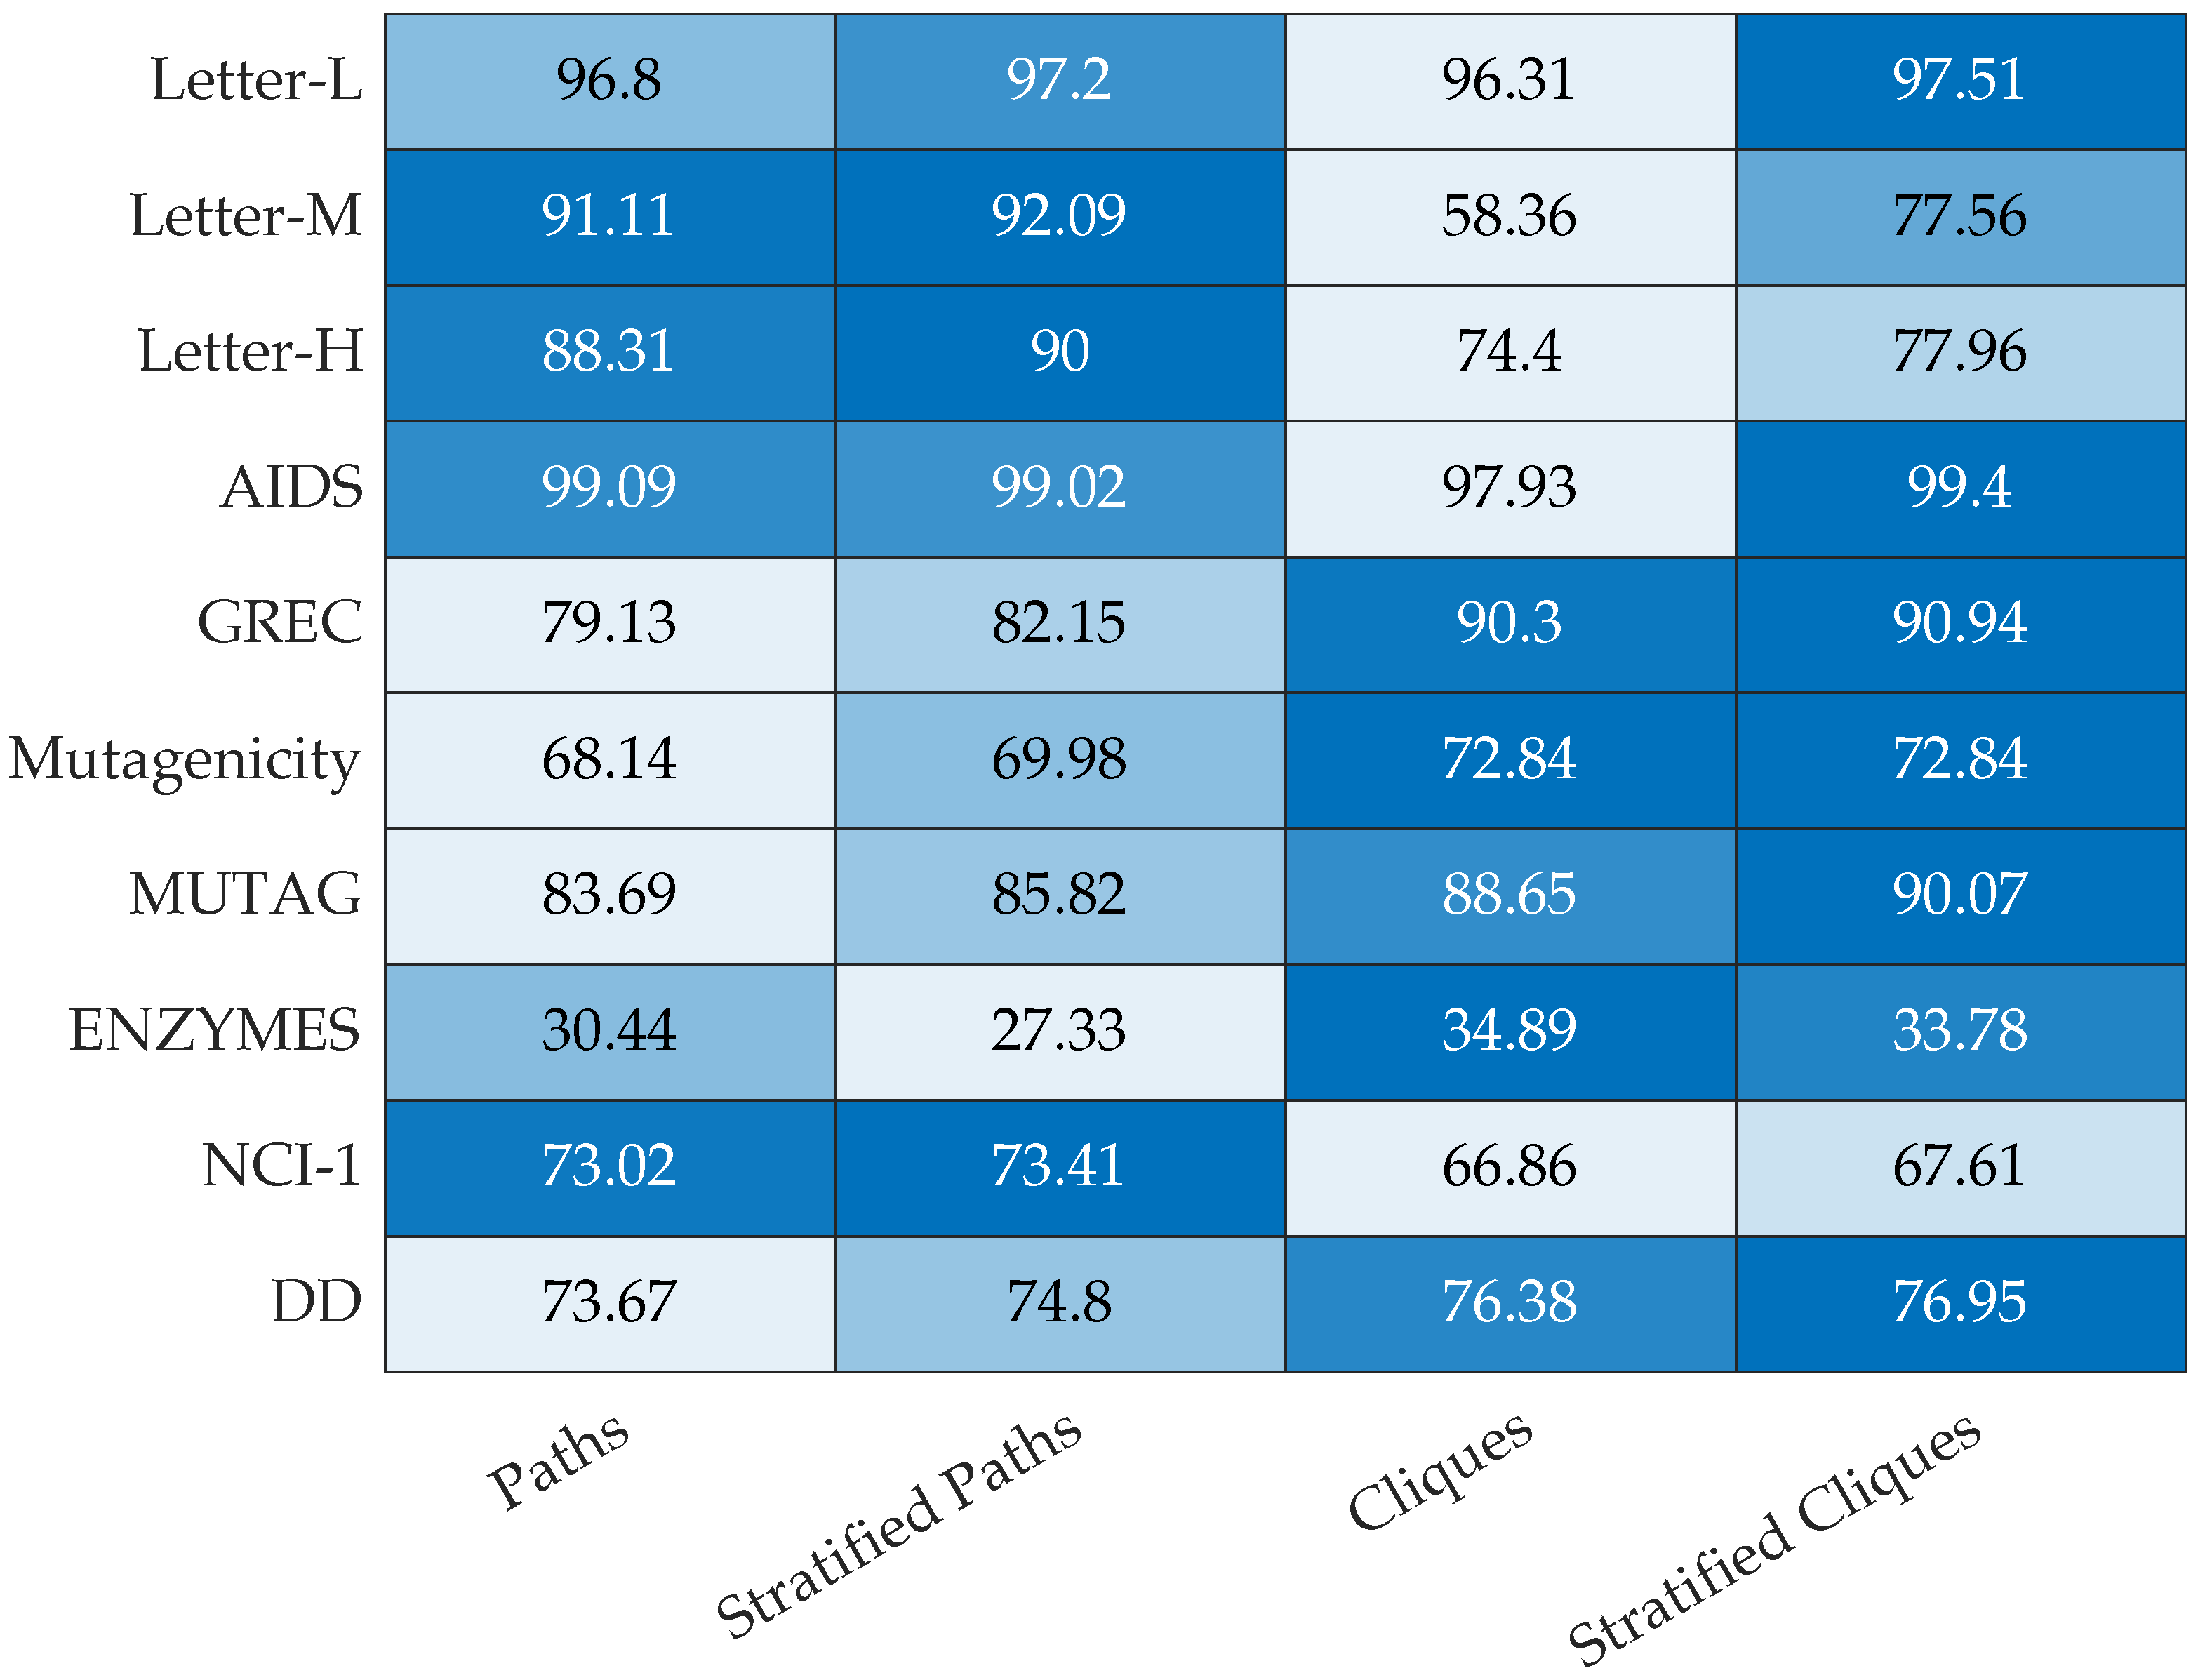
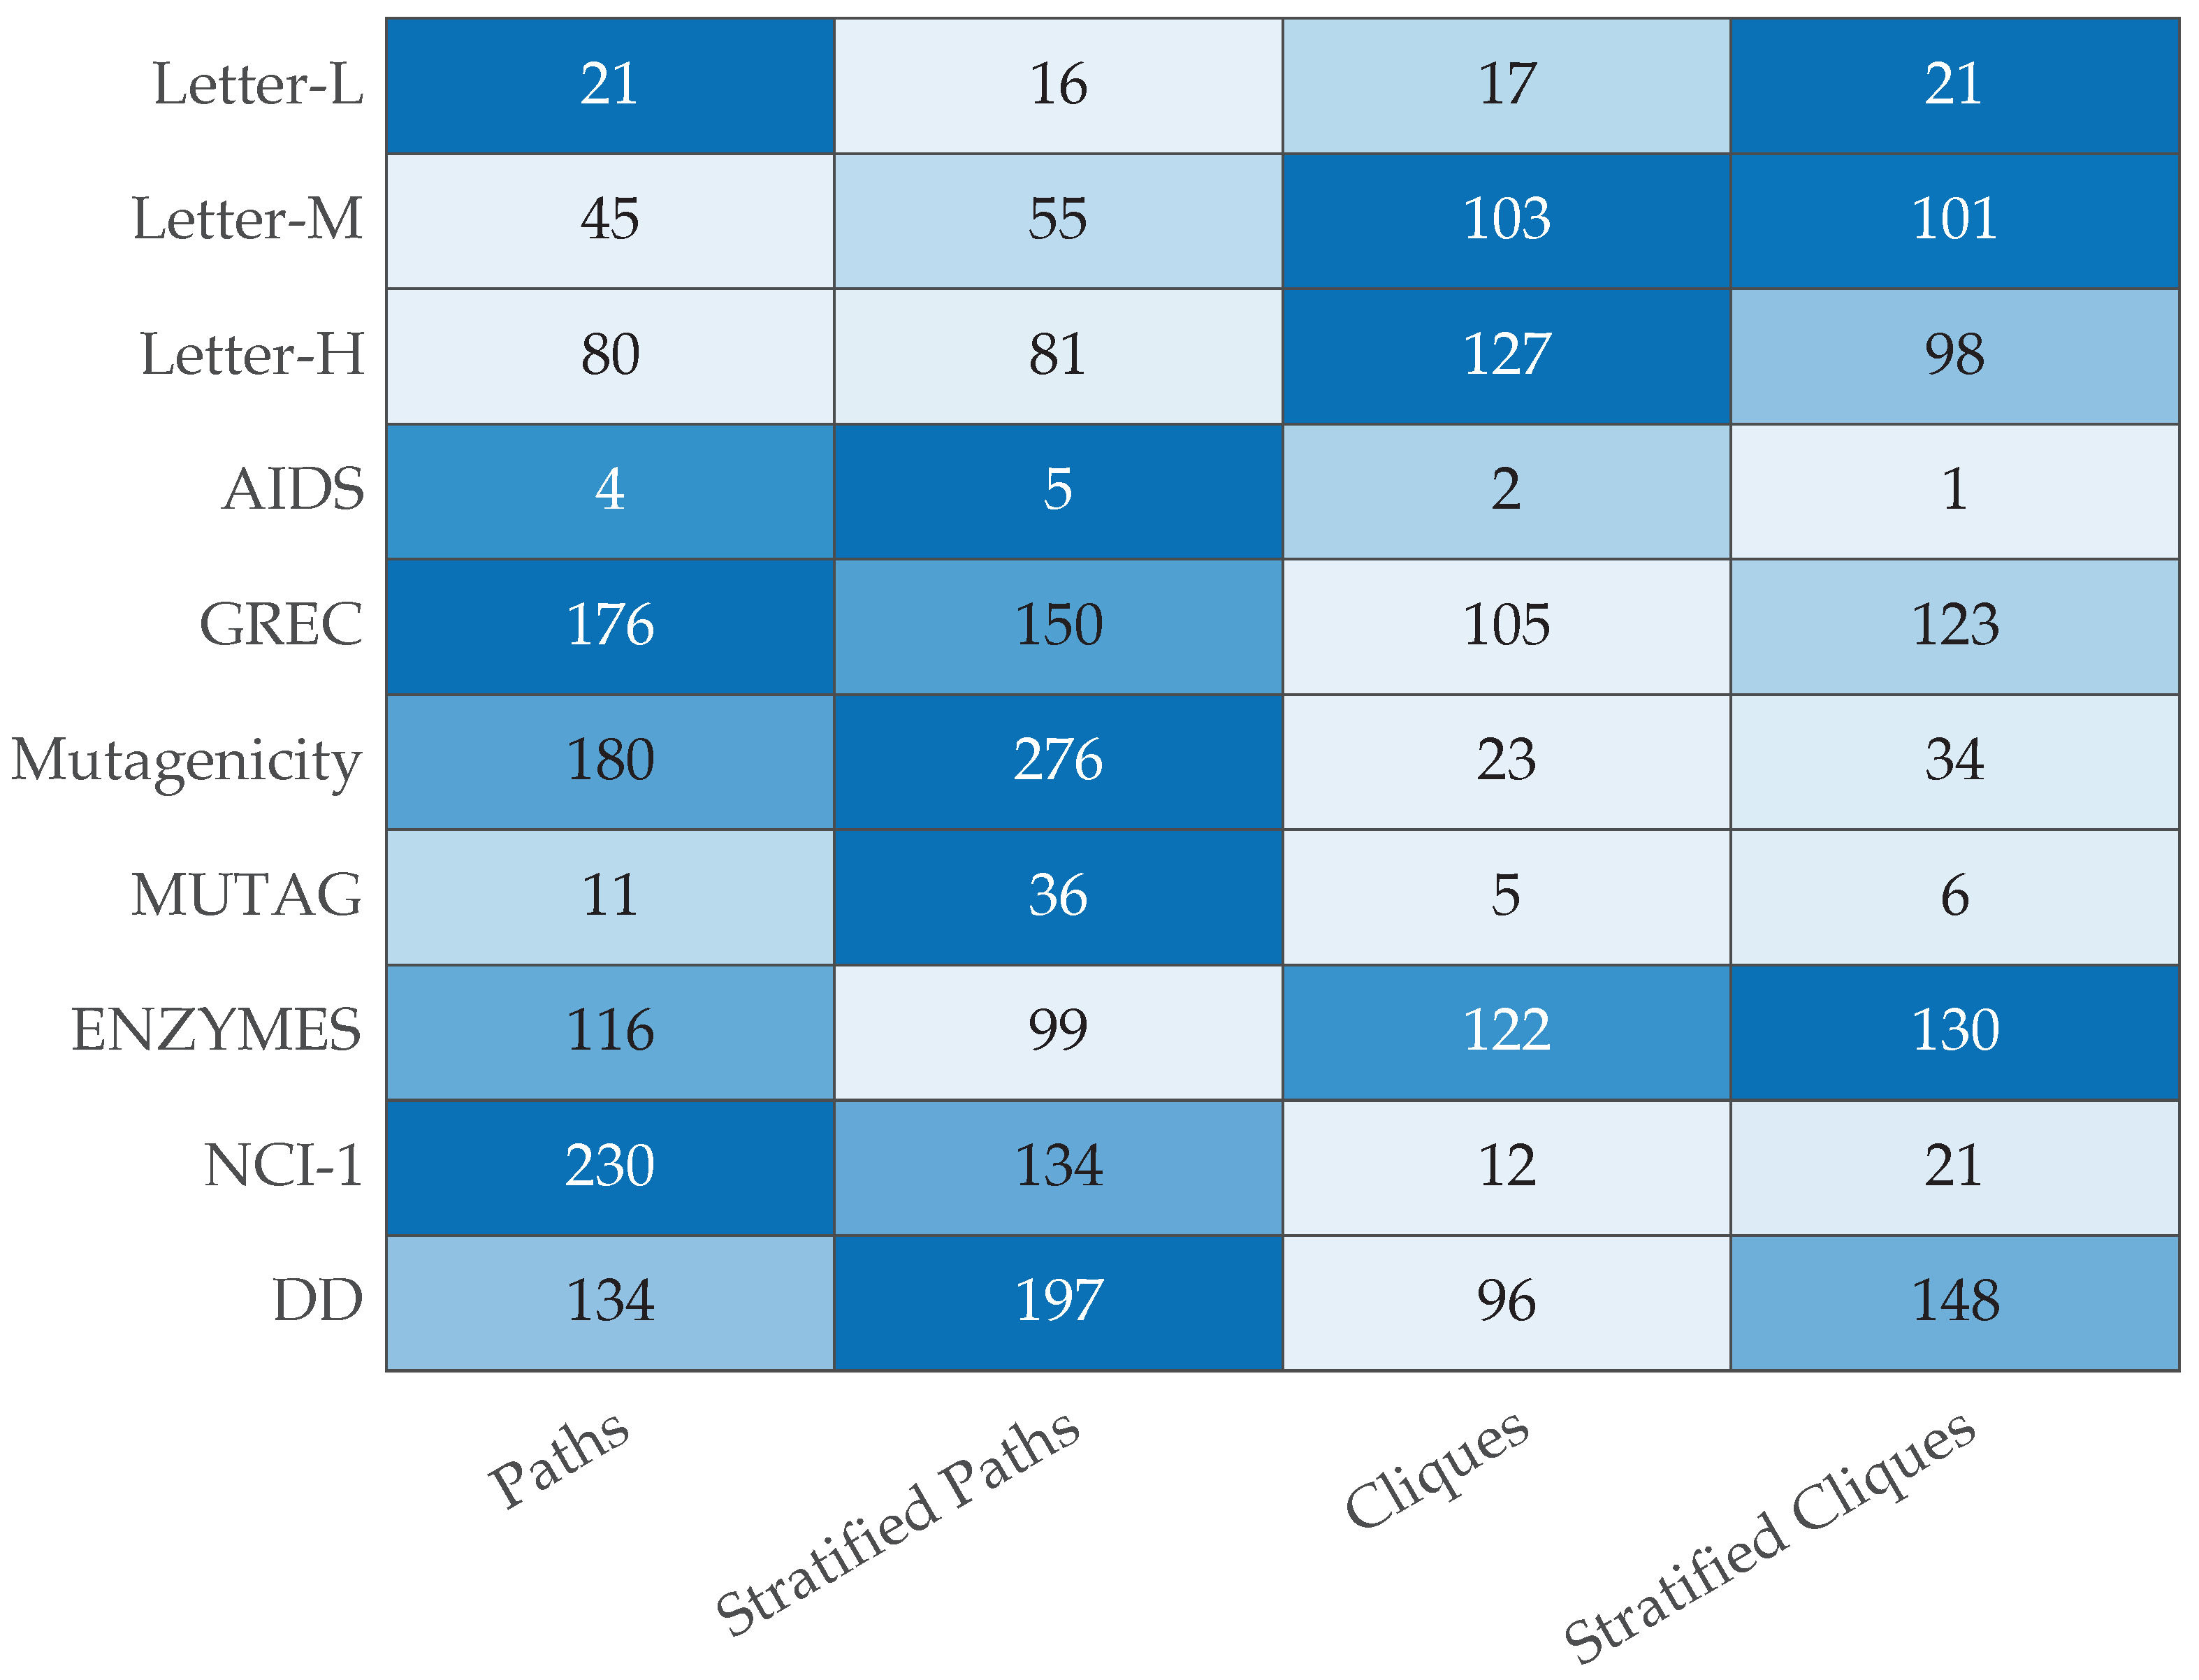
Granular Computing is a powerful information processing paradigm, particularly useful for the synthesis of pattern recognition systems in structured domains (e.g., graphs or sequences). According to this paradigm, granules of information play the pivotal role of describing the underlying (possibly complex) process, starting from the available data. Under a pattern recognition viewpoint, granules of information can be exploited for the synthesis of semantically sound embedding spaces, where common supervised or unsupervised problems can be solved via standard machine learning algorithms. In this work, we show a comparison between different strategies for the automatic synthesis of information granules in the context of graph classification. These strategies mainly differ on the specific topology adopted for subgraphs considered as candidate information granules and the possibility of using or neglecting the ground-truth class labels in the granulation process. Computational results on 10 different open-access datasets show that by using a class-aware granulation, performances tend to improve (regardless of the information granules topology), counterbalanced by a possibly higher number of information granules.
Keywords: structural pattern recognition; supervised learning; graph classification; inexact graph matching; granular computing; information granulation; data mining and knowledge discovery structural pattern recognition; supervised learning; graph classification; inexact graph matching; granular computing; information granulation; data mining and knowledge discovery