


Abstract
Classifying power quality disturbances (PQDs) under strong noise conditions remains challenging for existing deep learning models. These models typically separate denoising from feature extraction, often rely on attention mechanisms that operate along only a single dimension, and tend to achieve high accuracy at the cost of high complexity, which limits their performance under low signal-to-noise ratio conditions and hinders practical deployment. To address these limitations, this paper proposes AD-PDAF-Net, which organically integrates three key mechanisms through a co-design strategy. Unlike conventional methods that depend on preprocessing, an adaptive soft thresholding denoising layer is embedded into a lightweight residual network to progressively suppress noise during feature extraction, thereby unifying denoising with feature learning. A parallel dual attention module independently refines features along the channel and temporal dimensions, then adaptively fuses them using learnable weights to capture both frequency domain and temporal characteristics of disturbances. The lightweight network entry replaces aggressive downsampling with small convolutions to preserve transient details, and a bidirectional long short-term memory network (BiLSTM) efficiently captures temporal dependencies. Evaluated on a dataset of 25 disturbance categories defined in IEEE Std 1159-2019, the model achieves a classification accuracy of 97.26% and a Kappa coefficient of 97.02% under 20 dB white Gaussian noise, along with an accuracy of 98.78% under mixed noise conditions. The model has only 0.36 million parameters and a computational cost of just 1.50 GFLOPS. Through this co-design, AD-PDAF-Net achieves both high noise robustness and high classification accuracy with minimal computational overhead, offering an effective solution for time series signal recognition in resource constrained environments.
1. Introduction
Driven by the global energy transition and the goal of carbon neutrality, power systems are undergoing profound changes. The widespread integration of renewable energy sources and power electronic devices has granted the system greater flexibility, yet it has also introduced increasingly severe power quality challenges. Power quality disturbances (PQDs) such as voltage sags, harmonics, and transient oscillations can interfere with sensitive equipment in critical sectors like precision manufacturing and data centers, leading to substantial economic losses [1,2,3]. Therefore, reliable classification of PQDs under strong noise conditions has become an urgent requirement for the safe and stable operation of power systems.
Early methods relied on wavelet transform or S transform to extract handcrafted features, which were then fed into shallow classifiers [4,5,6]. Their performance was limited by fixed thresholds and manually designed features, often failing under varying noise conditions [7,8]. Deep learning models offer an alternative by learning features directly from data [9,10,11,12] and can achieve reasonable results under ideal conditions. However, when deployed in real industrial environments, they face three persistent issues. Most deep architectures lack built-in noise suppression mechanisms; they either assume clean inputs or rely on preprocessing, leading to sharp performance degradation under low signal-to-noise ratio (SNR) conditions [13]. Feature optimization is another common shortcoming, as approaches that treat all channels equally or use attention mechanisms along only a single dimension fail to capture both frequency domain and temporal characteristics of different disturbances [14,15,16]. High accuracy often comes at the cost of high complexity, with large models being slow to train and difficult to deploy for real-time monitoring. Under strong noise conditions at 20 dB, the accuracy of many mainstream models falls below 92% [12].
Existing methods typically handle denoising, feature optimization, and efficiency separately, making it difficult to address all three within a single framework. To solve these problems, this paper proposes AD-PDAF-Net, which organically integrates three mechanisms through a co-design strategy rather than simply stacking existing techniques.
The first mechanism targets noise suppression. Unlike conventional methods that treat denoising as an independent preprocessing step, an adaptive soft thresholding denoising layer (ASDL) is directly embedded into a lightweight residual network. This layer learns channel specific thresholds from the data and progressively suppresses noise during feature propagation, allowing denoising to proceed in parallel with feature learning and avoiding the disconnect between preprocessing and training objectives.
The second mechanism addresses feature optimization. A parallel dual attention adaptive fusion module (PDAF) operates independently along the channel and temporal dimensions. The channel attention submodule identifies informative frequency bands, while the multi-scale self-attention submodule captures temporal patterns at varying scales. The outputs of the two are fused using learnable weights, enabling the network to decide autonomously whether to emphasize frequency content or transient timing based on the characteristics of the input signal. This design contrasts with single attention or serial fusion strategies, which often lose complementary information.
The third mechanism focuses on efficiency. The network entry uses small convolutions instead of aggressive downsampling to preserve transient details, while the BiLSTM [17,18] network, which models long-range dependencies, maintains a compact hidden layer size. Through this co-design, the model achieves a balance among noise suppression, feature optimization, and efficiency, maintaining high accuracy without incurring high complexity.
Based on the above design, we comprehensively evaluated AD-PDAF-Net on a simulated dataset of 25 types of disturbances constructed according to IEEE Std 1159-2019 [19], analyzing its performance in terms of classification accuracy, noise robustness, computational efficiency, and internal feature representation.
2. Model Design
2.1. Overall Network Architecture
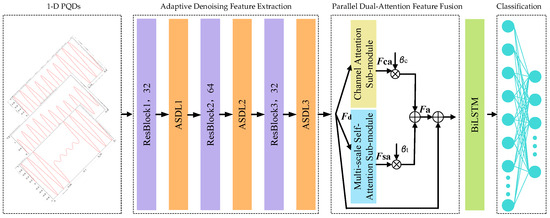
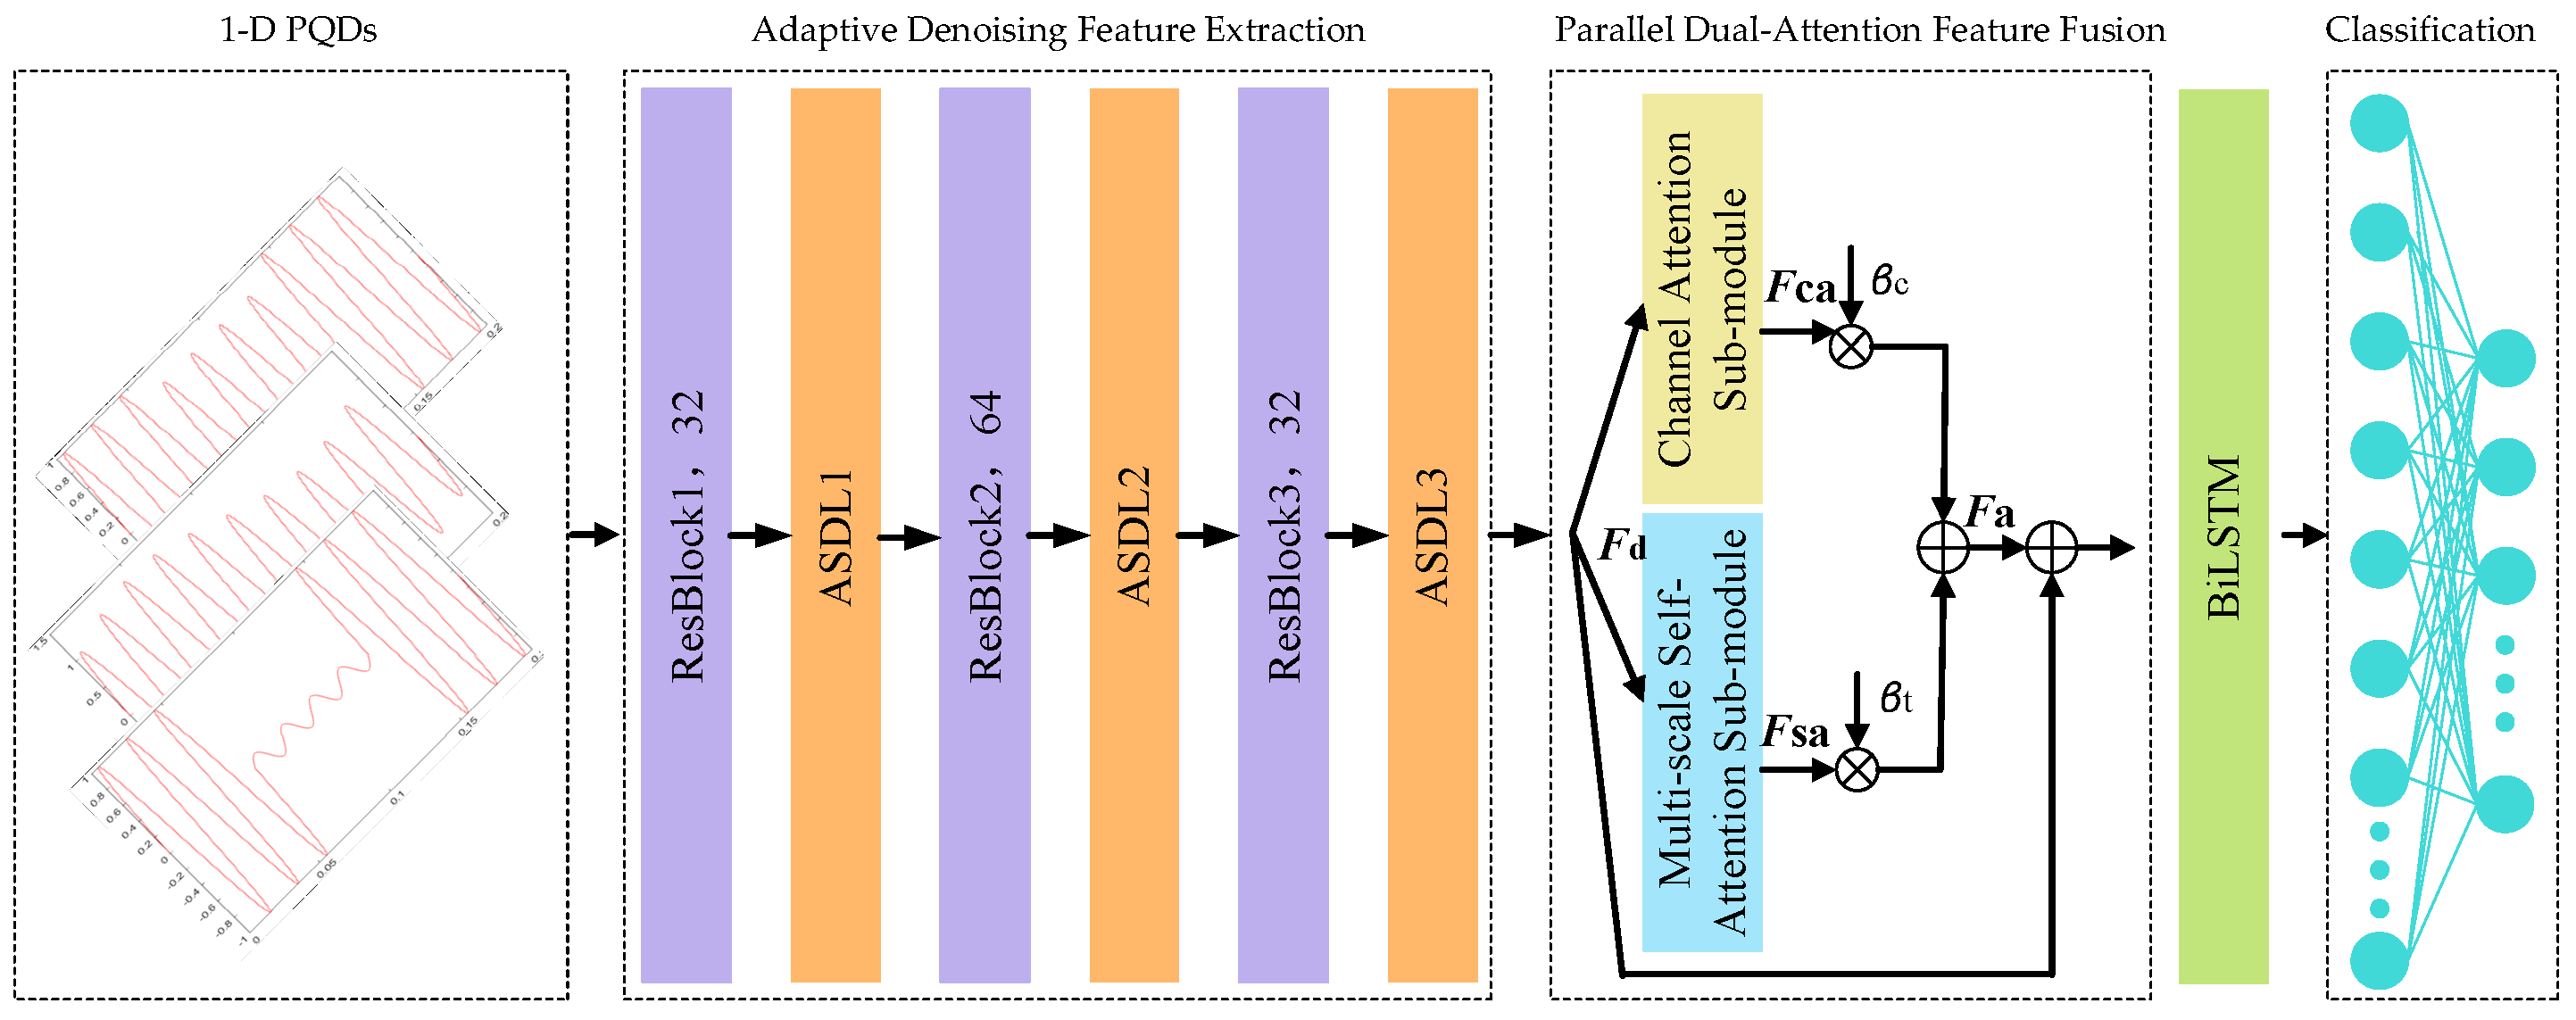
Figure 1 illustrates the overall architecture of AD-PDAF-Net. The model adopts a progressive suppress–refine–model framework to achieve robust classification of noisy PQDs. Its core design follows a hierarchical information processing pipeline, moving from feature extraction with integrated denoising to feature refinement and fusion, before proceeding to temporal context modeling and final classification.
Figure 1.
Overall architecture of the proposed AD-PDAF-Net model.
Given a 1D PQD signal sequence , where denotes the raw signal length, the model processes it through four core modules:
- Adaptive Denoising Feature Extraction: This module comprises a series of improved residual blocks, each embedded with an ASDL, to perform progressive noise suppression during feature extraction. It outputs a denoised feature map , where and denote the channel count and sequence length, respectively.
- Parallel Dual-Attention Feature Fusion: This module collaboratively refines by integrating a Channel Attention (CA) sub-module and a Multi-scale Self-Attention (MSA) sub-module in parallel. The outputs are adaptively fused via learnable dynamic coefficients, yielding an enhanced feature map , where and represent its channel count and sequence length, respectively.
- Temporal Context Modeling: A BiLSTM network encodes the feature sequence . By processing the sequence in both forward and backward directions, the BiLSTM captures long-range dependencies. The final hidden states from both directions are concatenated into a global temporal feature vector , where is the hidden state dimension.
- Classification: The feature vector h passes through a global pooling layer and a fully connected layer, which maps it to a probability distribution over the K disturbance categories.
Through this progressive design, the architecture systematically integrates adaptive noise suppression, multi-dimensional feature cooperative optimization, and deep temporal modeling capabilities, forming a versatile deep learning solution for PQD signal classification under strong noise. The detailed design of each module is elaborated in the subsequent subsections.
2.2. Adaptive Denoising Feature Extraction Module
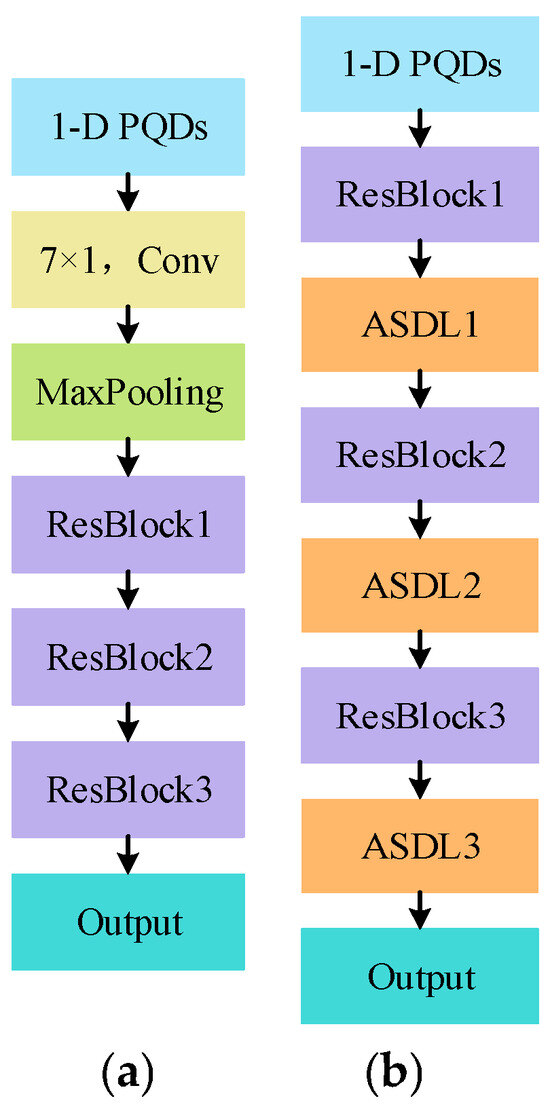
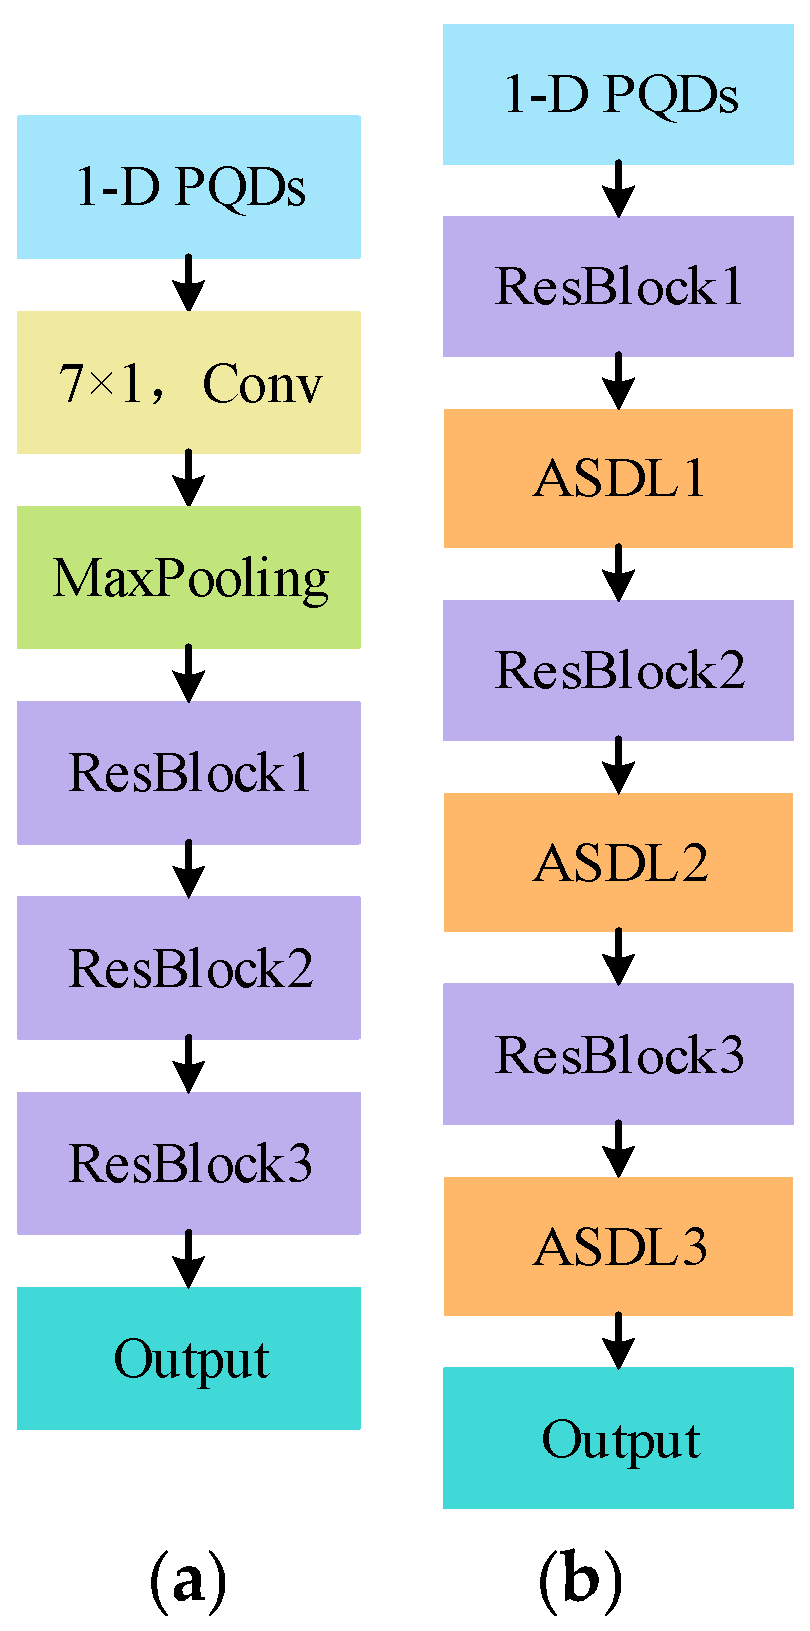
The adaptive denoising feature extraction module serves as the model front-end, designed to extract noise-robust preliminary features from noisy inputs. This architecture incorporates lightweight modifications (Section 2.2.1) along with the deep embedding of ASDLs (Section 2.2.2) to achieve concurrent feature extraction and progressive noise suppression. Figure 2 compares the proposed denoising front end with the standard adapted 1D ResNet-18 baseline.
Figure 2.
Architecture comparison between the adaptive denoising feature extraction module and the standard 1D ResNet-18 baseline. (a) Standard 1D ResNet-18 baseline; (b) Adaptive denoising feature extraction module.
2.2.1. Lightweight Architectural Modifications
To better adapt to 1D PQD signals containing high-frequency transients and to improve computational efficiency, the front end of the standard ResNet-18 is redesigned. The objective is to reduce model complexity while preventing the premature loss of critical discriminative information.
As shown in Figure 2, the original first layer—a stride-2 convolutional layer followed by a max-pooling layer—was replaced. Such aggressive downsampling can smooth out microsecond-level transient features. The specific modifications are:
- Removing the Large-Kernel Convolution and Pooling Layers: The initial convolutional layer and the subsequent max-pooling layer are discarded;
- Adopting a Lightweight Entry Point: A single stride-2 convolutional layer is adopted as the network entry. This design employs a smaller receptive field and a gentler downsampling rate, achieving the necessary dimensionality reduction while better preserving high-frequency details and transient structures;
- Maintaining Progressive Abstraction: The main network body retains the standard BasicBlock residual units. By carefully setting the stride of the first layer in each residual group, the model achieves orderly channel expansion and gradual temporal reduction, facilitating multi-level feature learning from local details to discriminative patterns.
This lightweight redesign significantly reduces parameters and computational cost while delivering a feature stream with superior temporal resolution and higher fidelity to the subsequent denoising layers.
2.2.2. Adaptive Soft-Thresholding Denoising Layer
Although the lightweight modifications improve the information fidelity of the feature flow, the extracted features remain contaminated by noise. To achieve simultaneous denoising during feature extraction, an ASDL is designed and embedded after each residual block. It filters the feature map from the preceding block to achieve progressive noise suppression across multiple levels of the feature hierarchy [20,21].
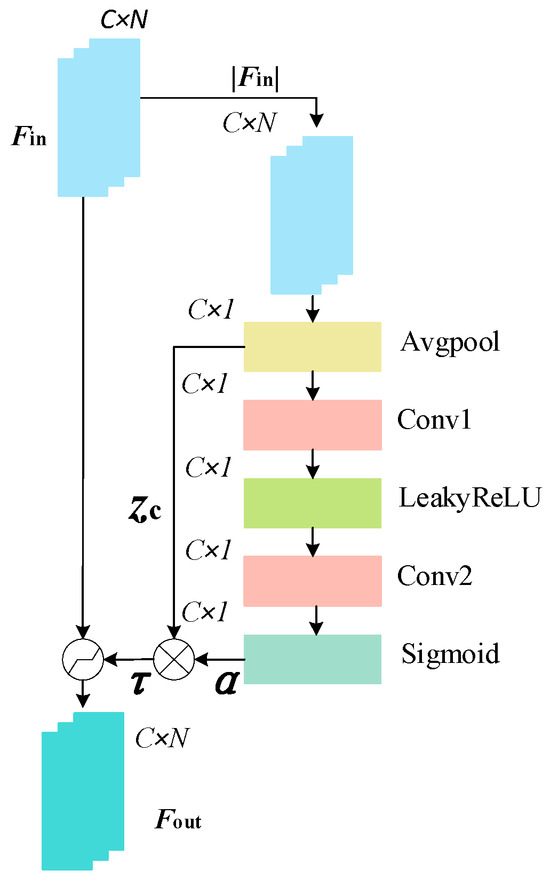
The internal structure of the ASDL is illustrated in Figure 3, which comprises three sequential operations: feature compression, threshold generation, and soft-thresholding filtering.
Figure 3.
Internal structure of the ASDL.
- (1)
- Feature Compression
Given the output feature map from a residual block (where C and N are the channel count and sequence length, respectively), global average pooling along the temporal dimension computes the mean absolute value for each channel. This yields a channel-wise statistic vector :
This vector encodes the global activity level per channel, serving as the basis for estimating channel-specific noise levels.
- (2)
- Threshold Generation
A lightweight sub-network then learns a channel-specific soft threshold from the vector z. This sub-network comprises two 1D convolutional layers (Conv1 and Conv1), each with a kernel size of 3 and stride of 1. Non-linearity is introduced by a LeakyReLU activation function (LReLU(·)) between them. A Sigmoid function (σ(·)) finally outputs a scaling coefficient α, yielding the threshold τ:
Here, denotes element-wise multiplication. This design ensures the threshold τ is dynamically adjusted according to the estimated noise level in each channel.
- (3)
- Soft-Thresholding Filtering
The learned channel-adaptive soft threshold is then applied to via the soft-thresholding function, producing the denoised output :
This operation shrinks to zero components in each channel with absolute values below the threshold (primarily noise) and contracts those above it (valid signal). The soft-thresholding function, , has a gradient of 1 for , ensuring stable gradients during backpropagation and allowing seamless integration as a differentiable module within the end-to-end training framework.
Embedding an ASDL after each residual block creates a “feature transformation → adaptive filtering” cascade. This design embeds noise suppression capability throughout the entire feature extraction network, enabling progressive, multi-scale noise filtering from shallow to deep layers. It thereby fundamentally enhances the robustness of the learned feature representations under low SNR conditions.
2.3. Parallel Dual-Attention Adaptive Fusion Module
Following processing by the adaptive denoising residual network in Section 2.2, noise interference in the feature map is significantly suppressed. However, for the task of PQD classification, different channels of the feature map—corresponding to different frequency components—and different temporal segments contribute unequally to the final classification [22,23]. To adaptively enhance these critical time-frequency features, a Parallel Dual-Attention Adaptive Fusion (PDAF) module is proposed.
The core design principle of this module is to refine the feature representation along two orthogonal dimensions independently: The Channel Attention (CA) sub-module performs global recalibration along the channel dimension (reflecting frequency distribution) to enhance discriminative frequency bands while suppressing redundant channels. The Multi-scale Self-Attention (MSA) sub-module models local-to-long-range dependencies along the temporal dimension (reflecting the time-domain waveform) to focus on key segments where transient events or periodic patterns occur.
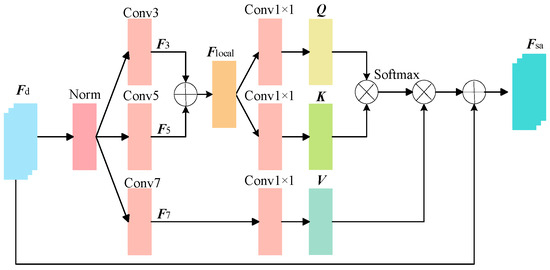
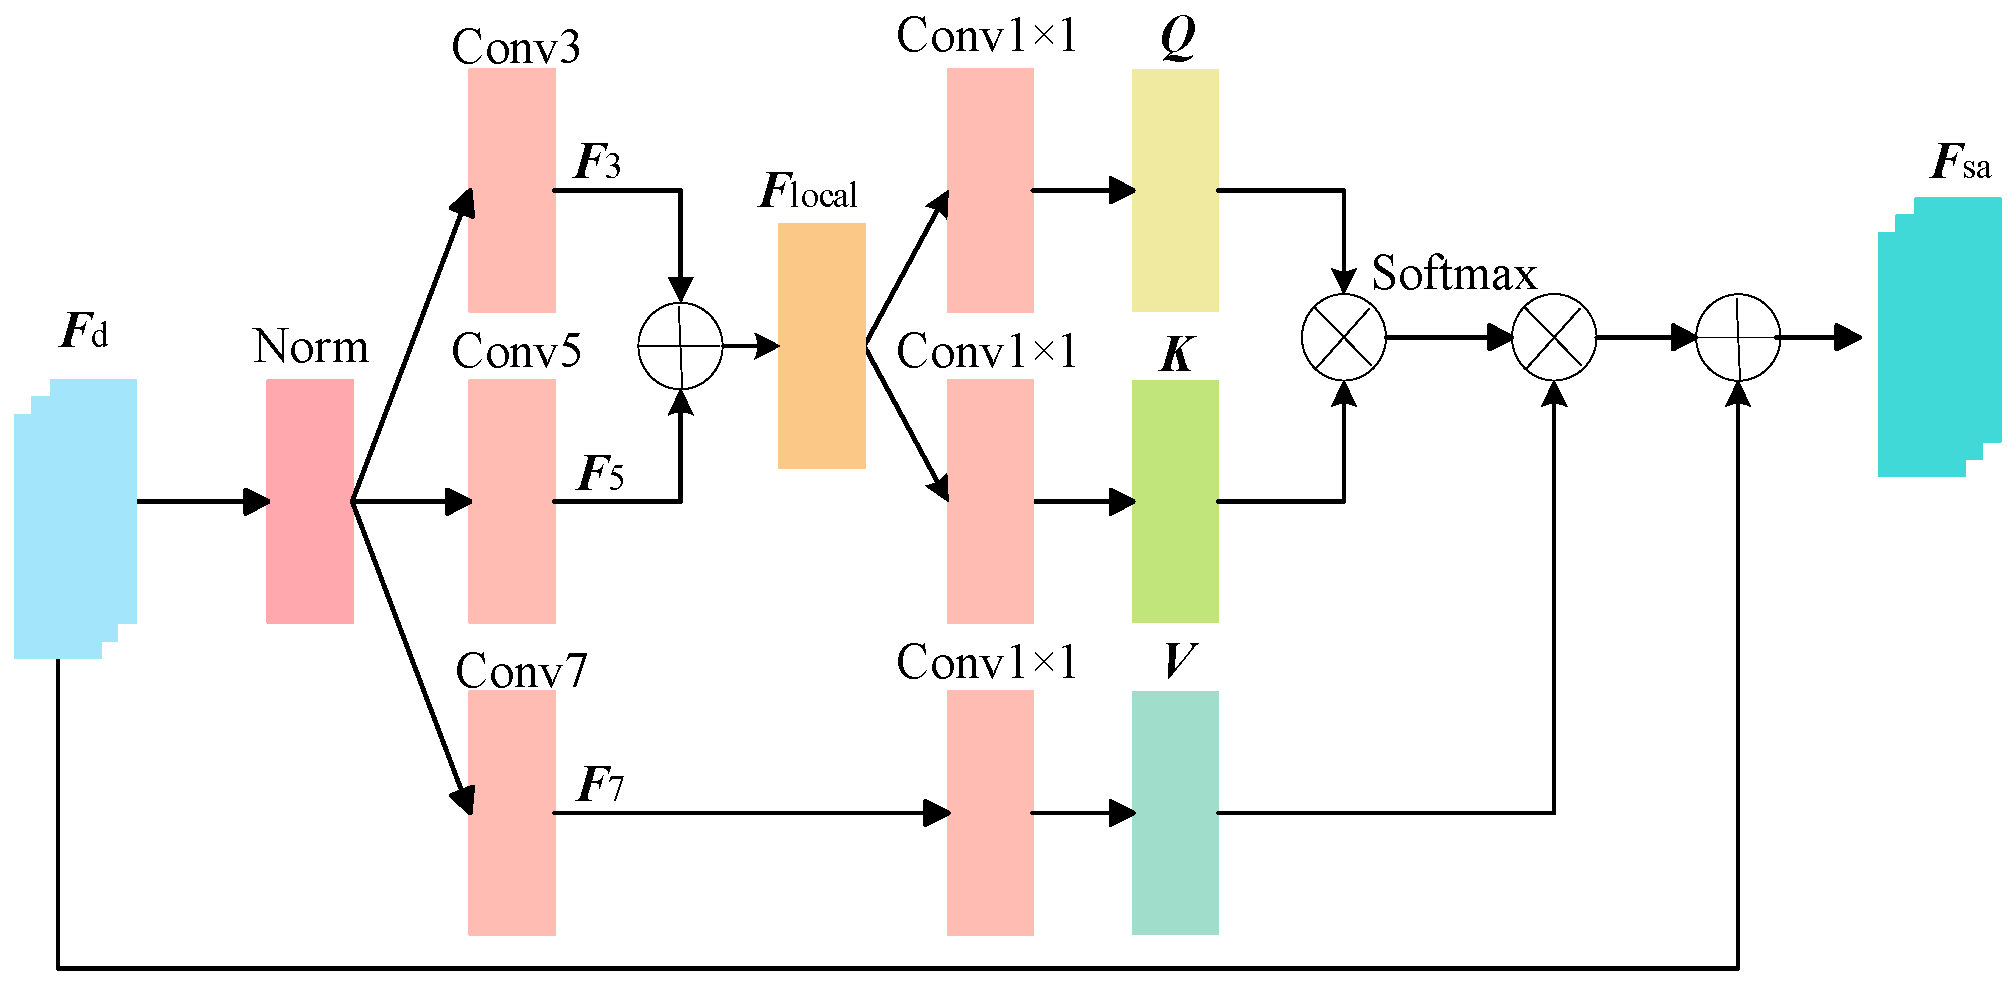
Both sub-modules process the same input feature map independently and in parallel. Their outputs are then adaptively integrated via a dynamic fusion strategy, allowing the network to flexibly balance its reliance on frequency-domain and time-domain features based on the specific characteristics of each input signal. The overall structure of the PDAF module is shown in Figure 4.
Figure 4.
Internal structure of the PDAF module.
2.3.1. Multi-Scale Self-Attention Sub-Module
To accurately capture and enhance key patterns at different temporal scales, this sub-module first applies Layer Normalization to the input feature . Subsequently, multi-scale feature extraction is performed in parallel using three convolutional kernels of different sizes:
The kernel sizes {3, 5, 7} are chosen to capture point-wise transients (e.g., voltage spikes), short-duration disturbance segments (e.g., interruptions), and long-range periodic patterns (e.g., harmonic oscillations), respectively.
To establish cross-scale temporal relationships, the features representing local dynamics, and , are summed to form a composite local feature . A directed attention mechanism is then employed: is projected separately to the Query (Q) and Key (K) matrices via independent 1 × 1 convolutional layers, while the feature representing long-range context, , is projected to the Value (V) matrix.
The temporally enhanced feature is obtained by computing the attention weights and aggregating the value vectors:
where is the dimension of the key vectors. The residual connection with the original input preserves foundational information and ensures training stability.
2.3.2. Channel Attention Sub-Module
To adaptively recalibrate the importance of each feature channel (or frequency band), this sub-module employs a classic squeeze-and-excitation structure. First, for the input feature map , global average pooling is applied along the temporal dimension N to generate a channel-wise statistic vector . The c-th element of u is calculated as:
This vector encodes the global average activation intensity of each channel, serving as the basis for assessing channel importance.
Subsequently, a channel-weighting vector is learned through a gating network with a bottleneck structure:
where and are the weight matrices of two fully-connected layers, denotes the ReLU activation function, is the Sigmoid function, and r is the compression ratio. The output feature map is finally obtained via channel-wise scaling:
This process automatically enhances feature channels that are more discriminative for the current classification task (e.g., specific frequency channels corresponding to harmonic disturbances) while suppressing redundant or noise-dominated channels, thereby achieving feature refinement in the frequency domain.
2.3.3. Dynamic Weight Fusion Strategy
To adaptively integrate the refined features from the temporal dimension () and the channel dimension (), a learnable dynamic fusion strategy is introduced. Two trainable scalar parameters, and , are defined. They are normalized into fusion weights and via a Softmax function:
where . The final output feature map is computed as their weighted sum:
The weights and are optimized via gradient descent during training. This data-driven fusion mechanism enables the network to autonomously learn an optimal feature integration strategy tailored to disturbances with different physical characteristics—such as steady-state harmonics versus transient events—without requiring prior knowledge. Consequently, it achieves adaptive and cooperative optimization between the time and frequency domains.
2.4. Bidirectional Long Short-Term Memory Network
To capture long-range temporal dependencies in power quality disturbances and to aggregate the locally refined features from preceding modules into a global representation, a BiLSTM network is employed [24,25].
The BiLSTM takes as input the feature sequence from the PDAF module, where T is the sequence length. It processes the sequence in both forward and backward directions, thereby comprehensively modeling the temporal evolution of disturbance events. The final hidden states from both directions at timestep T are concatenated to form a fixed-dimensional global temporal feature vector , which serves as input to the classifier:
where and denote the final hidden states of the forward and backward LSTMs, respectively.
By bidirectionally modeling the sequence , this module integrates long-range dependencies to produce a discriminative feature vector h that encapsulates the complete temporal context of the disturbance. This final abstraction provides a robust global basis for the classification decision.
3. Experimental Setup and Results
To systematically evaluate the efficacy of the AD-PDAF-Net model, a comprehensive validation is conducted from multiple dimensions, including classification accuracy, noise robustness, computational efficiency, and visualization of the internal mechanisms.
3.1. Experimental Setup
3.1.1. Dataset Construction and Noise Simulation
A standardized benchmark dataset containing 25 types of PQDs was constructed through numerical simulation in compliance with IEEE Std 1159-2019. The dataset comprises one category of normal signal, eight categories of single disturbances, and sixteen categories of composite disturbances, with specific categories and labels detailed in Table 1. All signals have a fundamental frequency of 50 Hz and a sampling frequency of 5.12 kHz, corresponding to 10 fundamental cycles (0.2 s duration) and 1024 data points per sample. Key parameters for single disturbances—such as magnitude, duration, and harmonic order—were randomly generated within the thresholds specified by the standard. Composite disturbances were generated via the temporal superposition of two or more single disturbances. The mathematical models and constraint conditions for all types of disturbances investigated in this study are provided in Table A1 of Appendix A.
Table 1.
25 Categories of PQD Signals and Their Labels.
To simulate the imbalanced occurrence frequency of disturbances in actual power grids, we adopted a non-uniform sampling strategy to construct the dataset. Specifically, 1000 samples were generated for normal signals and each of the 10 single disturbance categories, 600 samples for each of the 12 dual disturbance categories, and 400 samples for each of the 3 triple disturbance categories, resulting in a total of 18,400 clean samples covering 25 disturbance categories. The dataset was randomly split into training, validation, and test sets at a ratio of 7:2:1. To avoid information leakage, noise was added independently to each subset after the split, with additive white Gaussian noise at levels of 20 dB, 30 dB, and 40 dB applied to the three subsets. In addition, a separate mixed-noise test set was constructed, in which the signal-to-noise ratio for each sample was randomly selected with equal probability from {20 dB, 30 dB, 40 dB}.
3.1.2. Model Implementation and Training Details
The proposed AD-PDAF-Net was implemented using the PyTorch 1.13.1 framework. The specific software and hardware environment is detailed in Table 2, and the core hyperparameters are listed in Table 3. The adaptive denoising feature extraction module outputs a feature map of dimension 32 × 128. In the PDAF module, the channel attention sub-module employs a compression ratio , while the multi-scale self-attention sub-module uses convolutional kernels of sizes {3, 5, 7}. The hidden state dimension of the BiLSTM network is configured to 64.
Table 2.
Configuration of the Experimental Software and Hardware Computing Environment.
Table 3.
Detailed Parameter Configuration of the AD-PDAF-Net Model Architecture.
Training was conducted using a cross-entropy loss function and the Adam optimizer. Adam was selected because it effectively handles the diverse gradient sensitivities in AD-PDAF-Net, a heterogeneous architecture that integrates residual convolutions, dual-attention, and BiLSTM components. Empirical validation also showed that Adam achieves consistently optimal accuracy across different noise levels. The process utilized an initial learning rate of adjusted via a cosine annealing scheduler over 50 epochs with a batch size of 64. To enhance generalization and efficiency, a 0.2 dropout rate was applied before the final classifier, and automatic mixed-precision training was enabled.
To maintain statistical rigor, all performance indicators in this study are based on the average of 20 independent repeated runs, rather than a single experimental outcome.
3.1.3. Benchmark Models and Evaluation Metrics
To ensure a fair and comprehensive evaluation, three representative models with distinct architectures were selected as benchmarks: ResNet-LSTM (a CNN-RNN cascade), GAF-ResNet18 (based on time-frequency image classification), and DCNN (a 1D Deep Convolutional Network). All benchmark models were independently reproduced and trained under identical conditions regarding the software/hardware environment, dataset partition, and noise settings. Model performance was evaluated using four standard metrics: Accuracy, Recall, F1-score, and Cohen’s Kappa coefficient. Given the inherent class imbalance in the dataset, the Kappa coefficient was chosen as a core evaluation metric.
3.2. Results of Comprehensive Performance Comparison
3.2.1. Convergence Speed and Computational Efficiency
The convergence speed and computational efficiency of a model are critical for its practical deployment. Figure 5 presents the training convergence curves for all evaluated models under the 40 dB noise condition. In this scenario, AD-PDAF-Net achieved stable convergence within approximately 18 epochs, demonstrating a clear speed advantage over ResNet-LSTM (approximately 38 epochs) and GAF-ResNet18 (over 50 epochs). Furthermore, the convergence behavior across all other noise levels was examined, confirming that the model fully converges within the 50-epoch limit in every case. A detailed comparison regarding computational complexity and time cost is summarized in Table 4.
Figure 5.
Training curves of different models under 40 dB noise. The vertical dashed lines mark the positions where the training of each model ends.
Table 4.
Comparison of model complexity and computational efficiency.
The computational cost of AD-PDAF-Net is only 1.50 GFLOPS, substantially lower than that of GAF-ResNet18 (1125.51 GFLOPS) and ResNet-LSTM (8.55 GFLOPS), and even lower than the baseline model DCNN (4.04 GFLOPS). In terms of model size, AD-PDAF-Net also demonstrates significant advantages, comprising only 0.36 M parameters, far fewer than ResNet-LSTM (1.44 M) and DCNN (1.16 M). Its average training time (1.8 min) and inference time also outperform those of the more complex benchmark models. Although DCNN holds a slight advantage in time metrics due to its simpler architecture (0.99 min per epoch and 0.04 s per single-sample inference), AD-PDAF-Net achieves substantial improvements in classification accuracy and noise robustness under strong noise conditions (as verified in Section 3.3.2). In summary, AD-PDAF-Net achieves leading classification accuracy and noise robustness under strong noise conditions with extremely low computational cost (1.50 GFLOPS) and parameter count (0.36 M), striking a favorable balance between performance and efficiency.
3.2.2. Noise Robustness Test Results
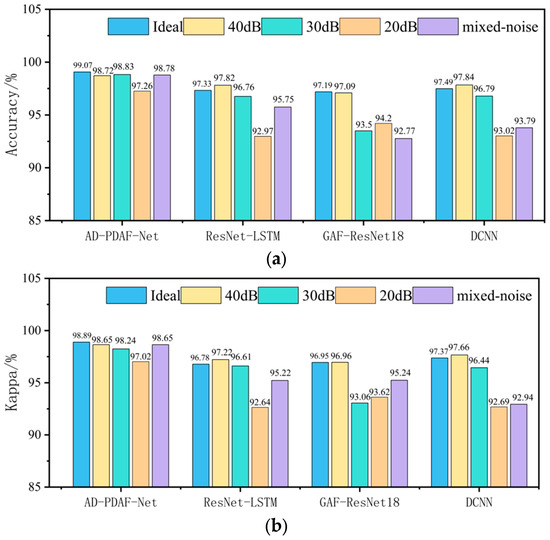
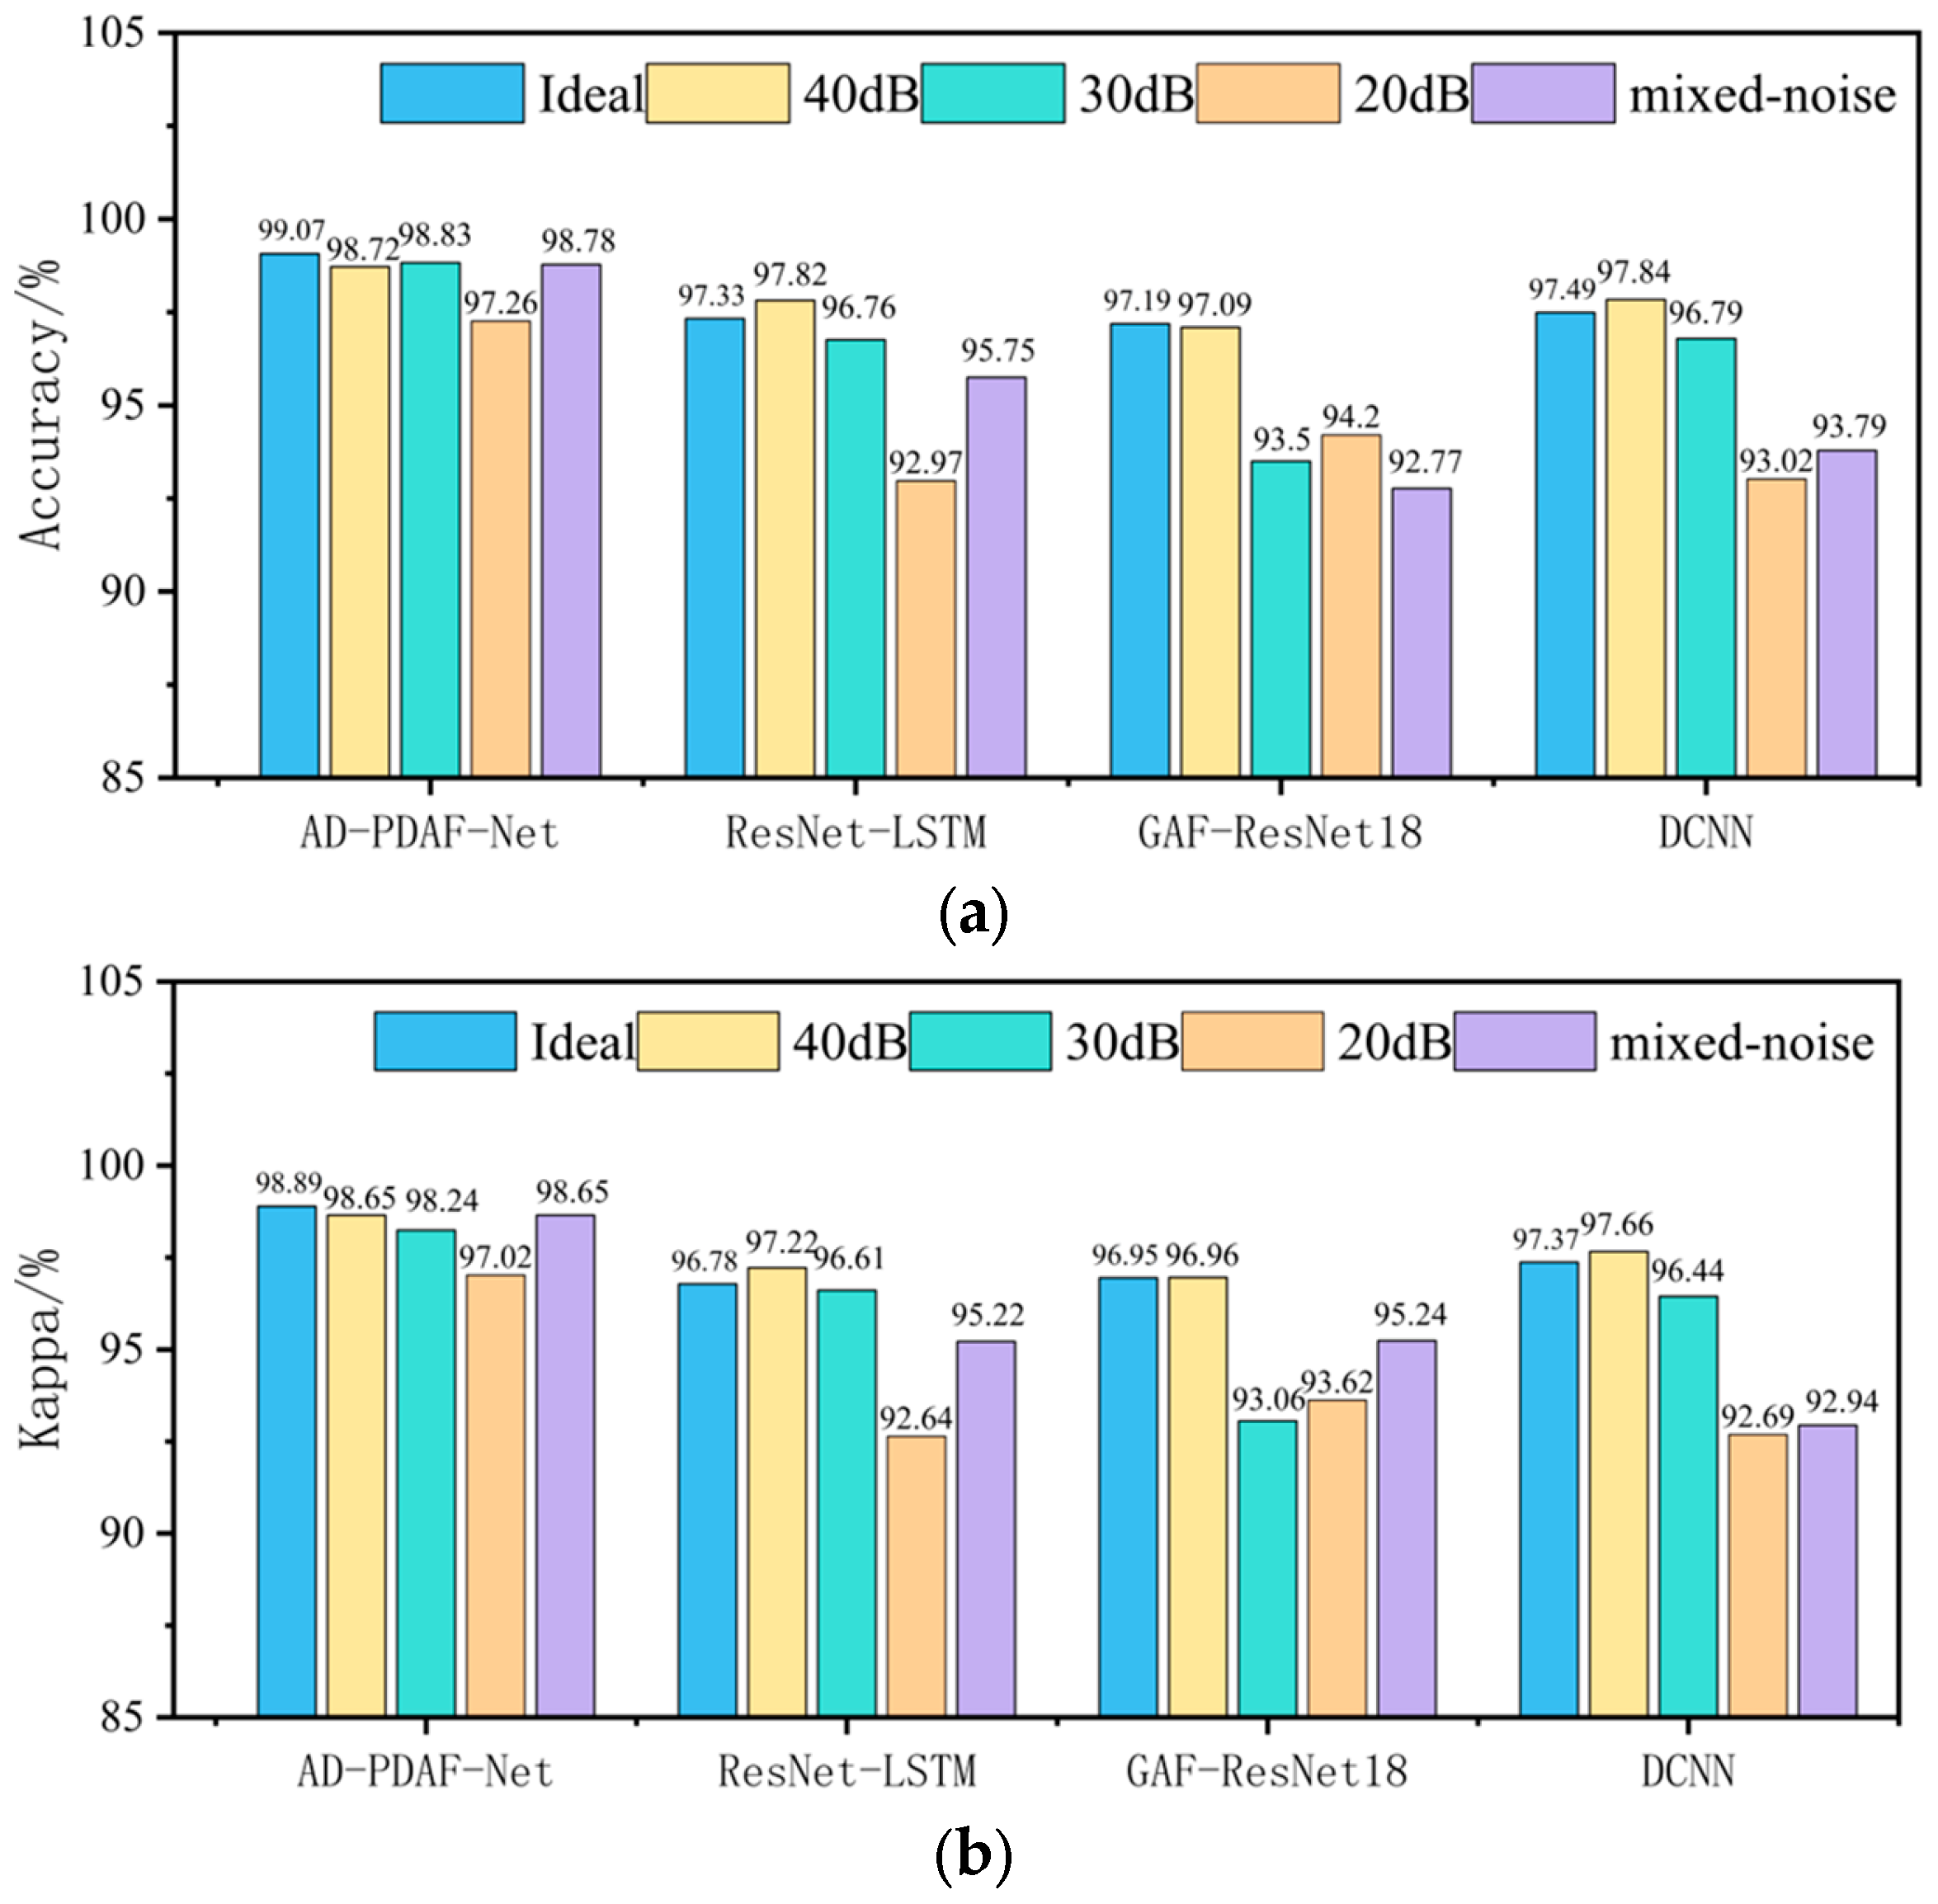
The comprehensive performance of each model under varying noise conditions is presented in Figure 6. Overall, the performance of all models decreased with increasing noise intensity. However, the proposed AD-PDAF-Net consistently achieved the highest average recognition accuracy and Kappa coefficient across all test conditions, while also exhibiting the most gradual performance degradation.
Figure 6.
Performance comparison of different models regarding noise robustness. (a) Accuracy of different models; (b) Kappa coefficients of different models.
Specifically, under the mild 40 dB noise condition, all models performed similarly, with AD-PDAF-Net attaining the highest accuracy of 98.72%. As the noise level increased to 30 dB and then to 20 dB, the relative advantage of AD-PDAF-Net became progressively more pronounced, achieving accuracies of 98.83% and 97.26%, respectively. Notably, under the challenging 20 dB strong-noise condition, both its accuracy (97.26%) and Kappa coefficient (97.02%) exceeded those of the second-best benchmark model by a margin of at least 3 percentage points.
On the mixed-noise test set, designed to simulate complex, non-stationary industrial noise, AD-PDAF-Net demonstrated exceptional stability, achieving an accuracy of 98.78%. Its Kappa coefficient (98.65%) declined by a mere 0.24% compared to the noise-free baseline—a reduction significantly smaller than the degradations observed for other models (which ranged from 1.56% to 4.43%). These results strongly validate the powerful robustness conferred by its adaptive mechanisms against time-varying and composite noise interference.
3.2.3. Performance Comparison with Existing Method
To situate the performance of AD-PDAF-Net within the broader research landscape, a trend comparison was conducted with four recent state-of-the-art methods based on diverse feature representation strategies. These include: TC + ResNet18 [26] (based on visual trajectory circles), LFAM + DSAM [22] (employing multi-level attention fusion), Dual-ResNet [16] (a 1D-2D parallel fusion model based on improved ResNet), and ER-MVCNN [27] (based on 3D visual helical curve images). It should be noted that due to differences in data generation, noise injection protocols, and SNR definitions across the referenced studies, the comparative results provided in Table 5 are intended primarily for indicative trend analysis.
Table 5.
Performance trend comparison with existing methods.
Under the most challenging condition of 20 dB strong noise, the average recognition accuracy of AD-PDAF-Net (97.26%) was significantly higher than that of all compared models (the best of which achieved 96.65%), highlighting its exceptional noise robustness. At 30 dB, its performance (98.83%) was comparable to the optimal result reported elsewhere (98.95%). Under noise-free conditions, AD-PDAF-Net (99.07%) maintained a high classification precision. It is noteworthy that at 40 dB, while the accuracy of AD-PDAF-Net (98.72%) was slightly lower than the best-reported result (99.24%), it still surpassed the performance of several other mainstream methods.
3.3. Ablation Study Results on Module Effectiveness
3.3.1. Ablation Study on Adaptive Soft-Thresholding Denoising Layers
An ablation study was conducted to precisely evaluate the contribution of the multiple Adaptive Soft-thresholding Denoising Layers (ASDLs) to the noise robustness of AD-PDAF-Net. Several model variants were constructed by sequentially removing these layers, with the results summarized in Table 6.
Table 6.
Ablation Study Results of the ASDLs under Different Noise Levels.
The results indicate that the effectiveness of the ASDLs increases significantly with noise intensity, demonstrating a clear additive effect. Under higher SNR conditions, such as the no-noise or 40 dB scenarios, removing one or two ASDLs had a limited impact on performance. Most variants maintained accuracy close to the complete model, with fluctuations typically within ±1%. In contrast, under the strong 20 dB noise condition, the absence of ASDLs led to a systematic performance decline. The complete model achieved an accuracy of 97.26%. When only two ASDLs were retained (ASDL1 + ASDL2, ASDL1 + ASDL3, ASDL2 + ASDL3), accuracy dropped to the range of 95.74–95.86%. Retaining only a single ASDL (ASDL1, ASDL2, or ASDL3) further reduced accuracy to 93.93–94.11%. The variant with all ASDLs removed yielded the lowest performance at 92.58%.
For variants retaining the same number of ASDLs, different layer combinations yielded similar performance. This suggests that the individual ASDLs function synergistically and complementarily in suppressing noise. The multi-layer, progressive noise-filtering architecture is therefore identified as a key factor enabling AD-PDAF-Net to maintain high recognition accuracy in strong noise environments.
3.3.2. Ablation Study on the Parallel Dual-Attention Adaptive Fusion Module
To verify the superiority of the Parallel Dual-Attention Adaptive Fusion (PDAF) module’s design, its performance was compared with three variants under 40 dB noise conditions: Channel Attention only (CA-only), Multi-scale Self-Attention only (MSA-only), and a Serial Fusion strategy where CA and MSA are applied sequentially. The experimental results are presented in Table 7. The full PDAF module achieved the best performance across all evaluation metrics. Its accuracy, F1-score, and Kappa coefficient were higher than those of the single-attention variants and significantly superior to the serial fusion strategy. This demonstrates that the parallel structure can more effectively leverage the complementary features from the temporal and channel dimensions, avoiding potential information loss inherent in sequential processing.
Table 7.
Ablation Study Results of Different Attention Mechanisms.
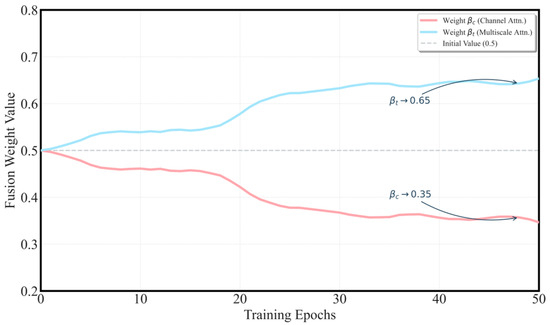
The evolution of the dynamic fusion weights during training is shown in Figure 7. The weights for the MSA output () and the CA output () were both initialized to 0.5, representing an equal-weight assumption for the two feature types. As training progressed, generally increased and stabilized around 0.65, while decreased accordingly to approximately 0.35. This dynamic adjustment indicates that the model autonomously learns to rely more on the temporal features refined by the MSA sub-module based on training feedback.
Figure 7.
Evolution of the dynamic fusion weights during training.
3.4. Visualization of Internal Model Behavior
3.4.1. Visualization of Feature Space Distribution Evolution
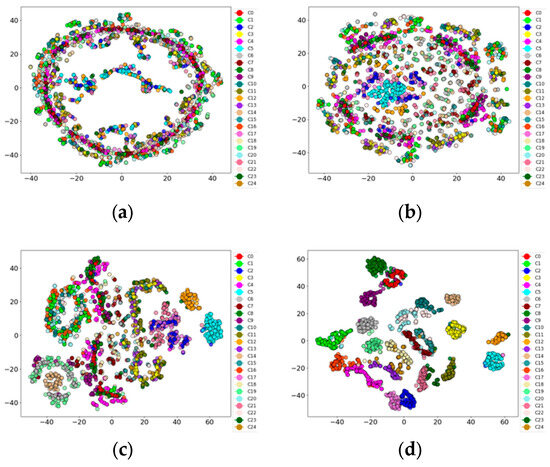
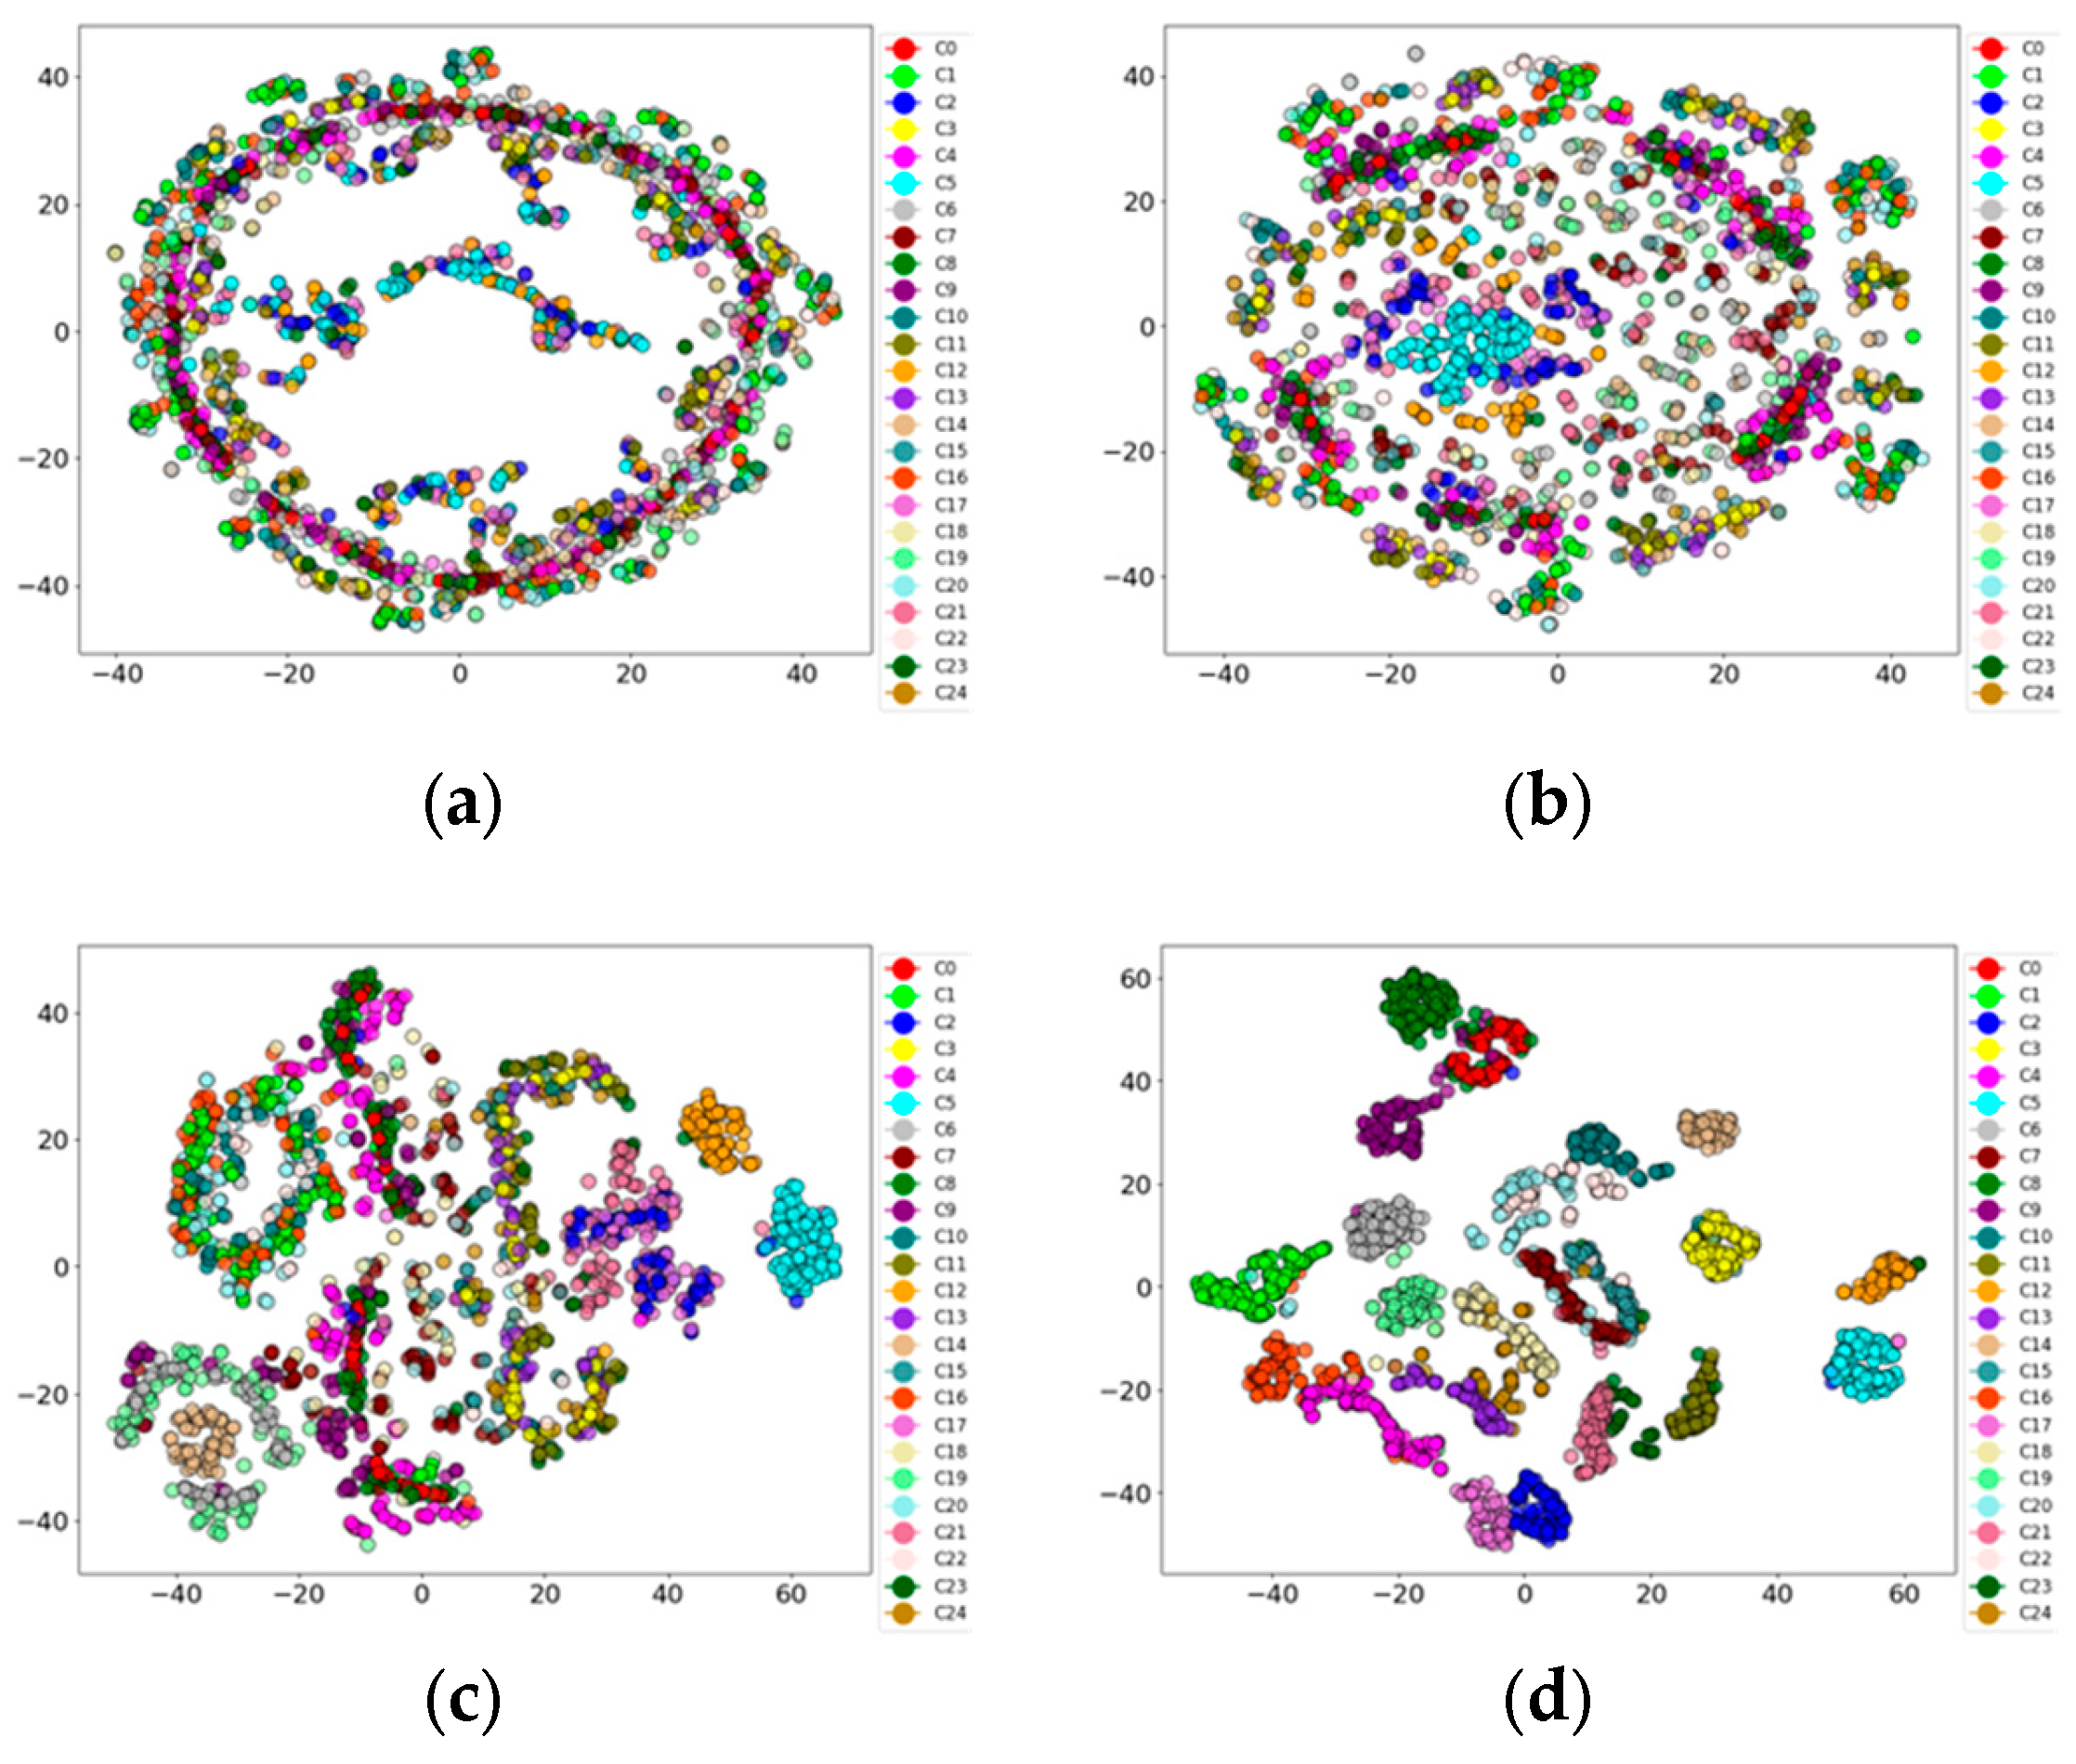
The evolution of feature separability across different stages is documented in Figure 8 using t-distributed stochastic neighbor embedding (t-SNE) visualization. While the original noisy signals in Figure 8a appear mixed and overlapping, the features after the adaptive denoising module in Figure 8b show an emerging clustering trend despite remaining inter-class overlap. The introduction of the PDAF module in Figure 8c leads to much tighter clusters and increased separation. Finally, Figure 8d illustrates that features after BiLSTM modeling form highly separable clusters, confirming the stepwise refinement from a noisy state to a discriminative representation.
Figure 8.
Evolution of feature space distribution across processing stages. (a) Original noisy signals; (b) Features after adaptive denoising module; (c) Features after PDAF module; (d) Features after BiLSTM modeling.
3.4.2. Visualization of Feature Map Activation Pattern Evolution
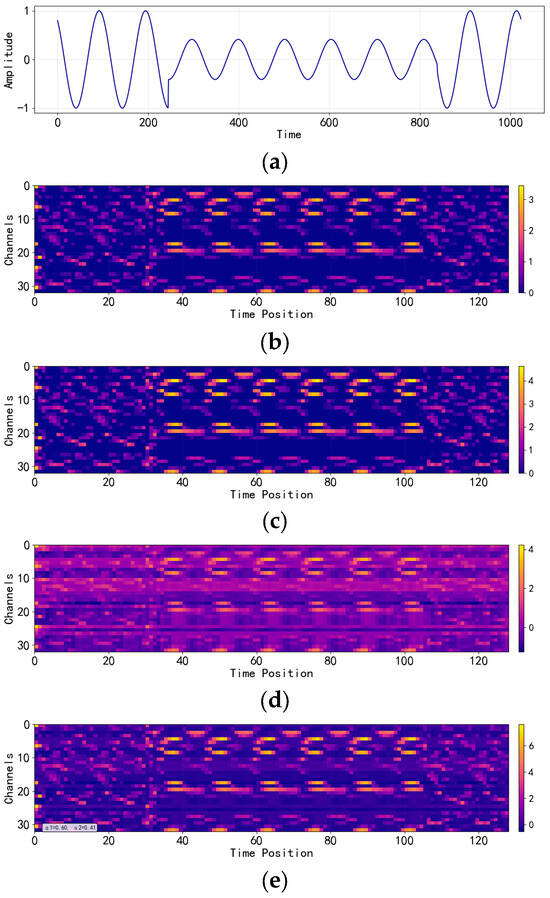
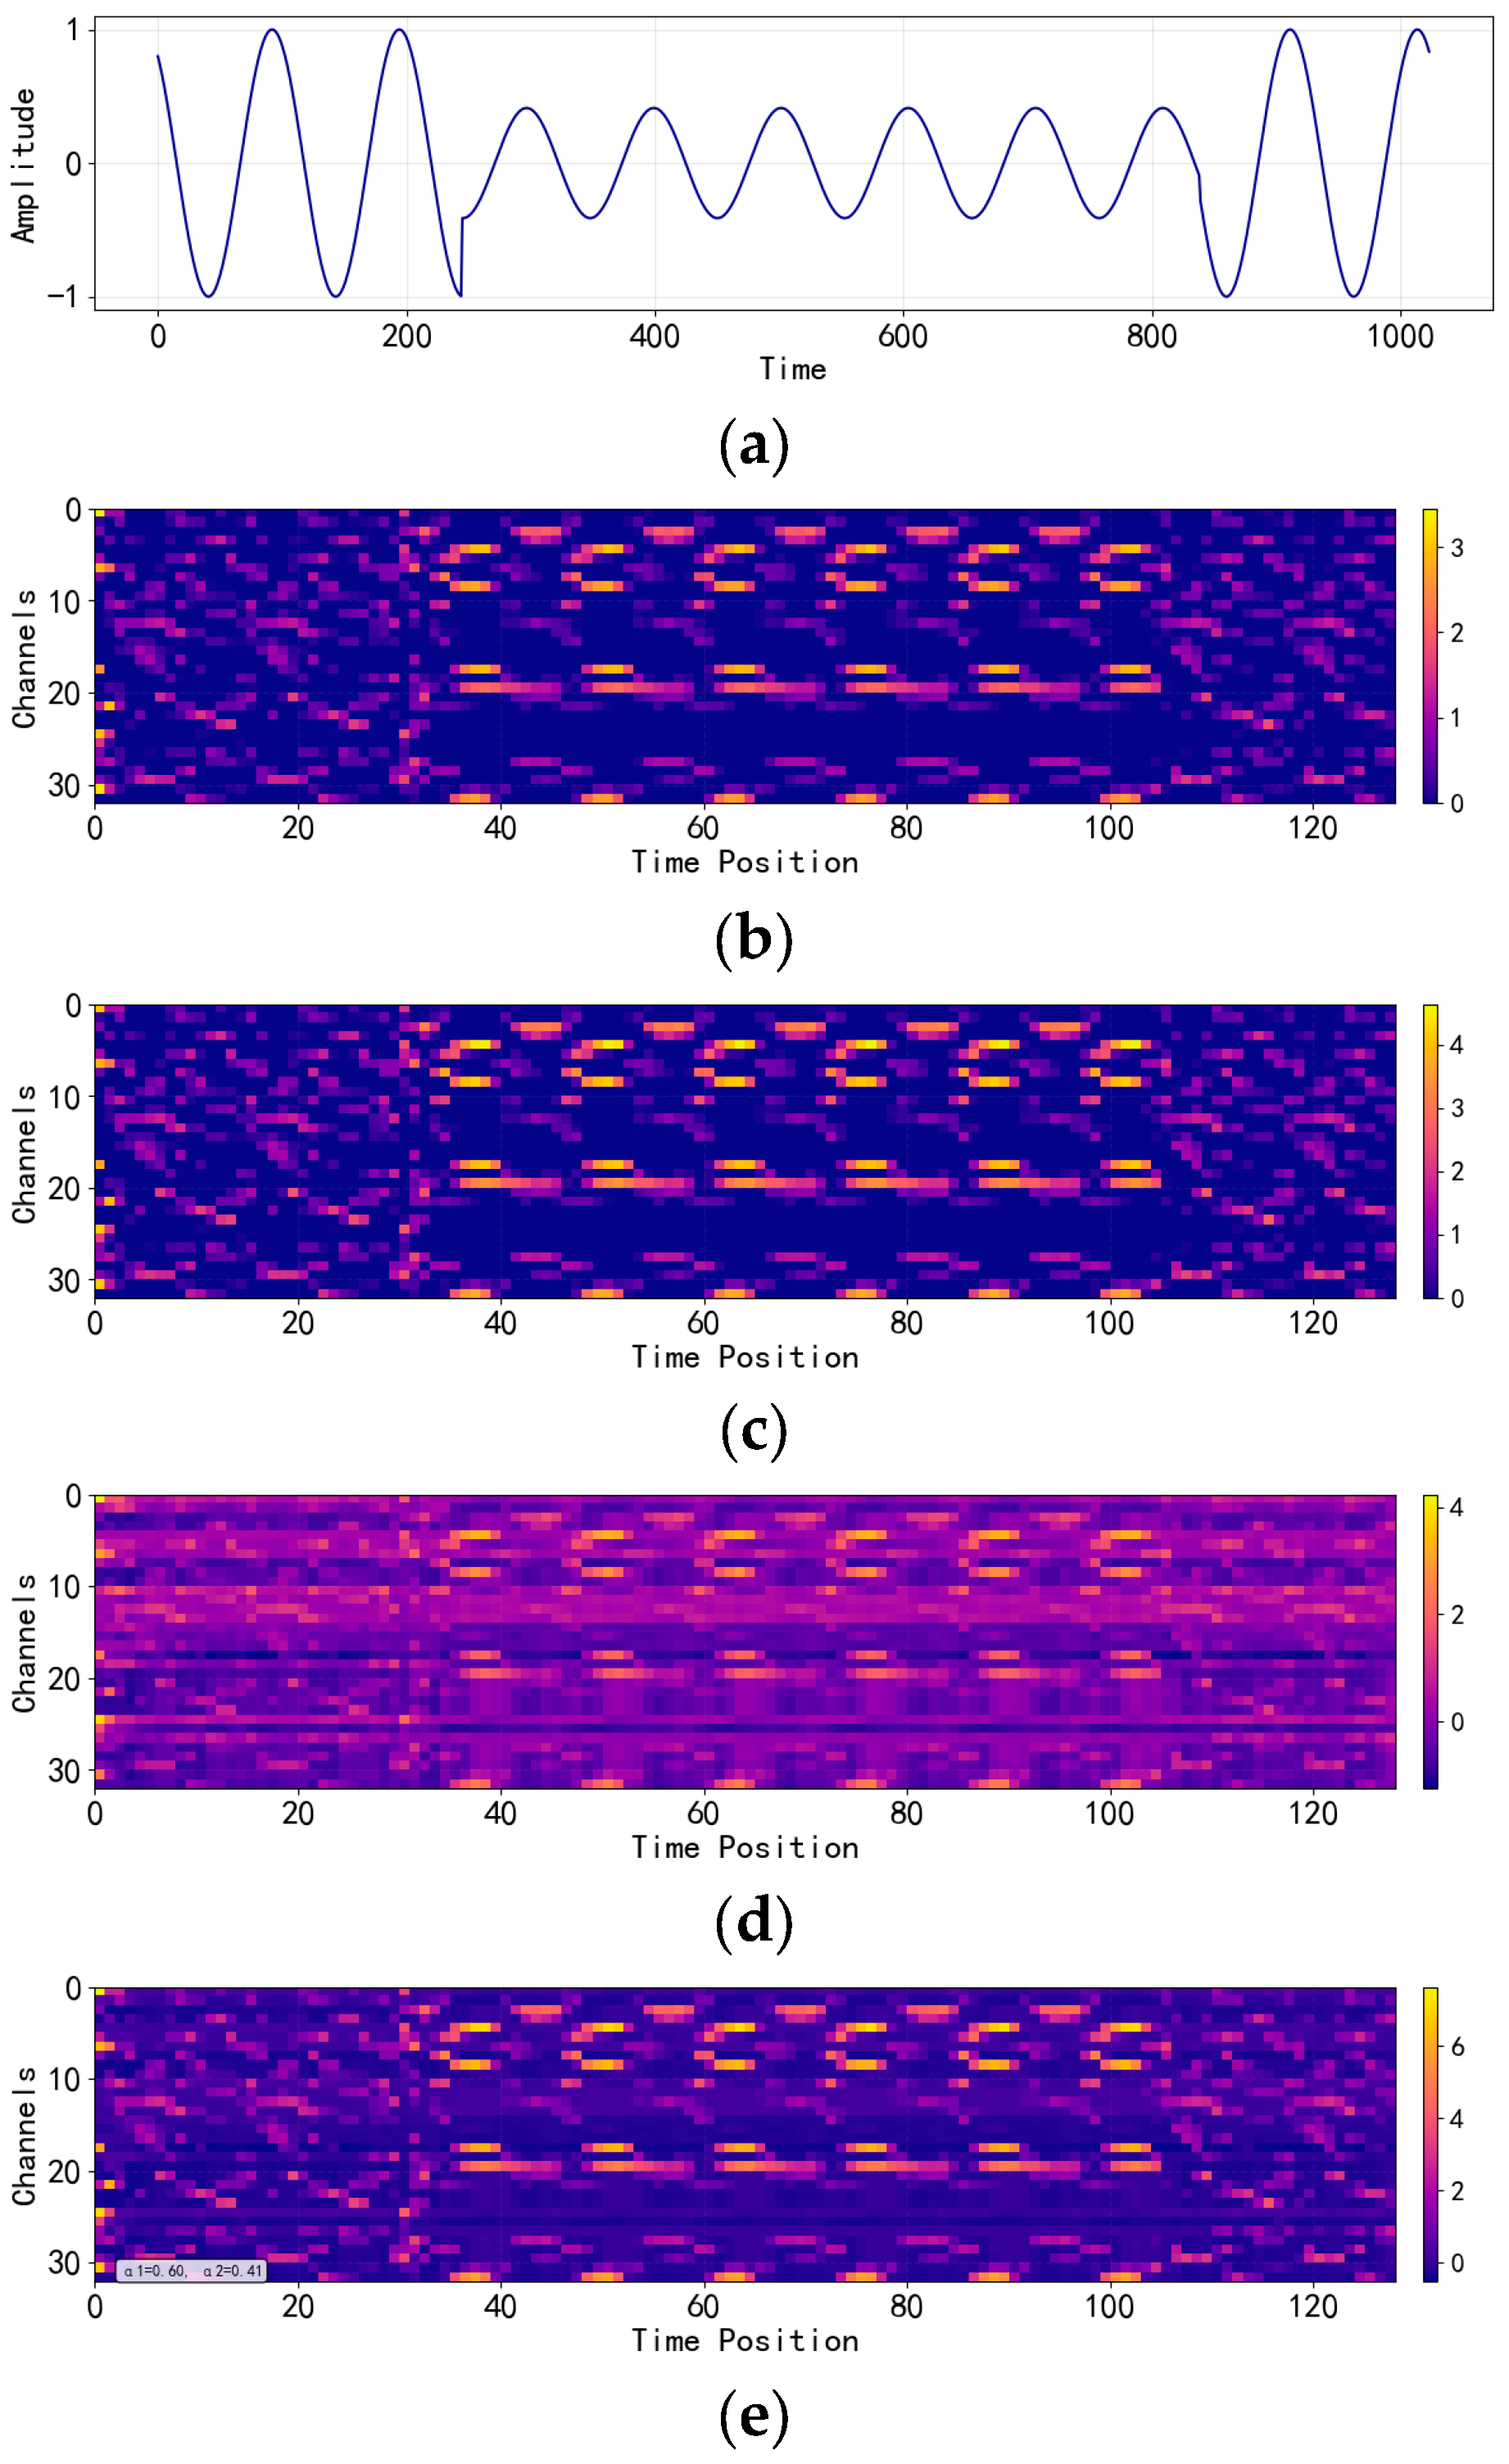
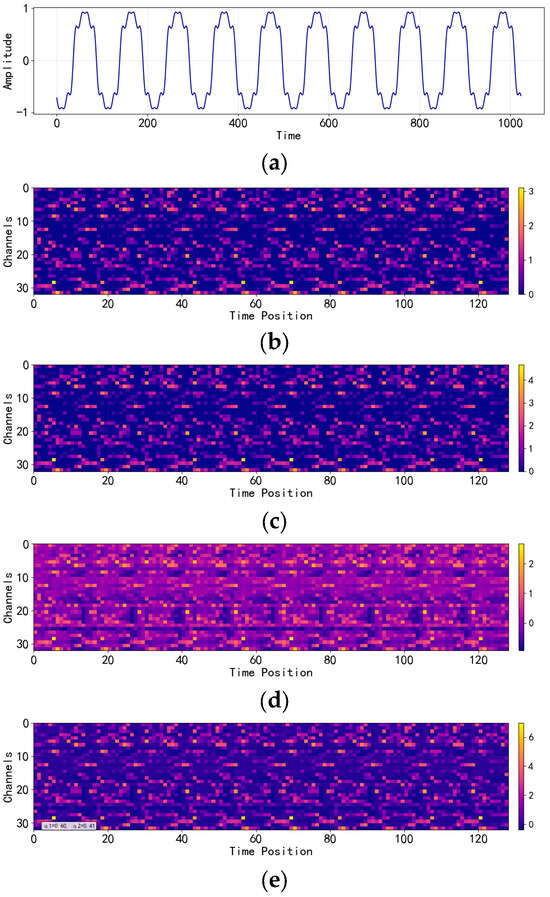
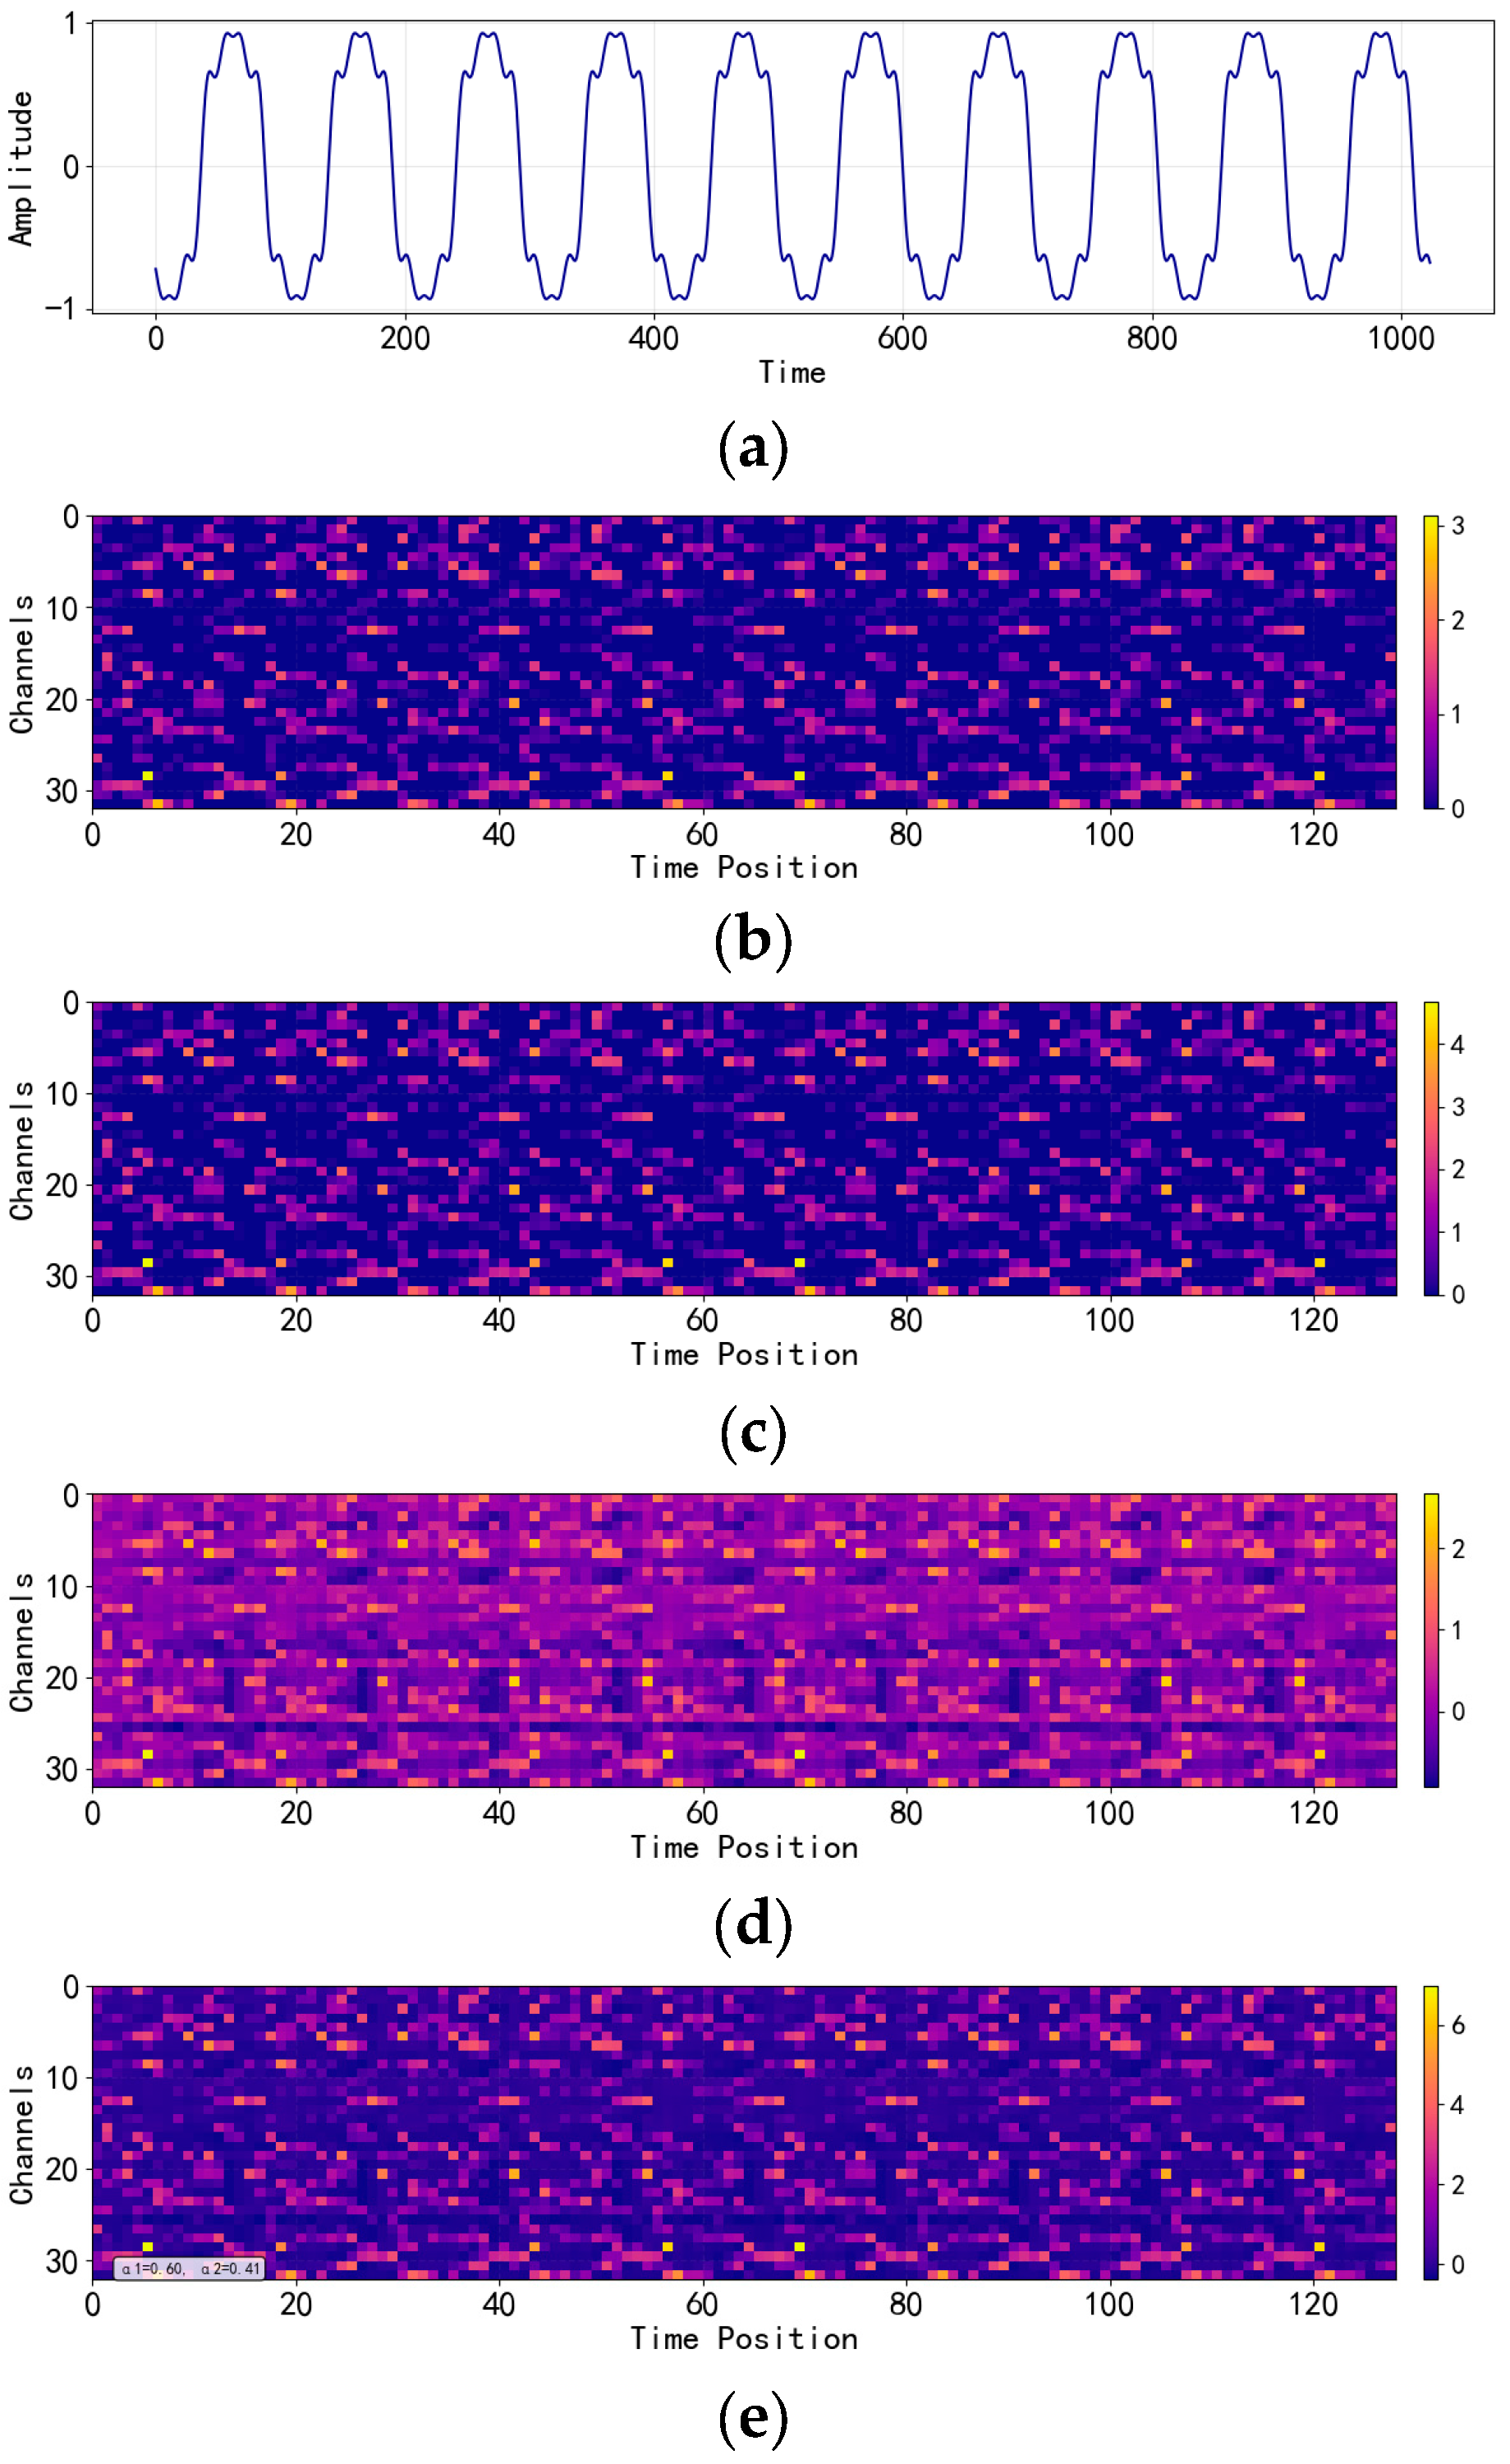
To illustrate the feature optimization process within the PDAF module, the activation patterns at key stages are visualized for two sample types: a voltage sag and a steady-state harmonic. All feature maps have dimensions of 32 channels × 128 sequence steps.
For the voltage sag sample (Figure 9), the original waveform is shown in Figure 9a. The primary feature map from the denoising front-end (Figure 9b) shows heightened activation in several channels, specifically during the sag period. The output of the CA sub-module (Figure 9c) maintains a similar spatial pattern. In contrast, the MSA sub-module output (Figure 9d) exhibits a global enhancement of activation across all channels within the same disturbance interval. The final fused features (Figure 9e) show an overall activation intensity between that of the CA and MSA outputs.
Figure 9.
Visualization of the feature evolution process for a voltage sag sample. (a) Input waveform; (b) Primary feature map; (c) CA output; (d) MSA output; (e) Final fused features.
For the harmonic sample (Figure 10), the original periodic waveform is shown in Figure 10a. Its primary feature map (Figure 10b) displays roughly periodic bright bands across multiple channels. The CA output (Figure 10c) reinforces this periodic pattern. The MSA output (Figure 10d) again shows a global, channel-wide brightness increase synchronized with the periodic intervals. The final fused features (Figure 10e) similarly exhibit an intermediate activation level.
Figure 10.
Visualization of the feature evolution process for a harmonic sample. (a) Input waveform; (b) Primary feature map; (c) CA output; (d) MSA output; (e) Final fused features.
The contrast is evident: activations for the sag sample are concentrated in specific local time segments, while those for the harmonic sample exhibit a periodic structure spanning all channels. The distinct spatio-temporal activation patterns for different disturbances demonstrate the PDAF module’s ability to adaptively optimize feature representations according to the underlying physical characteristics of the disturbance.
3.5. Recognition Results per Disturbance Category and Confusion Matrix
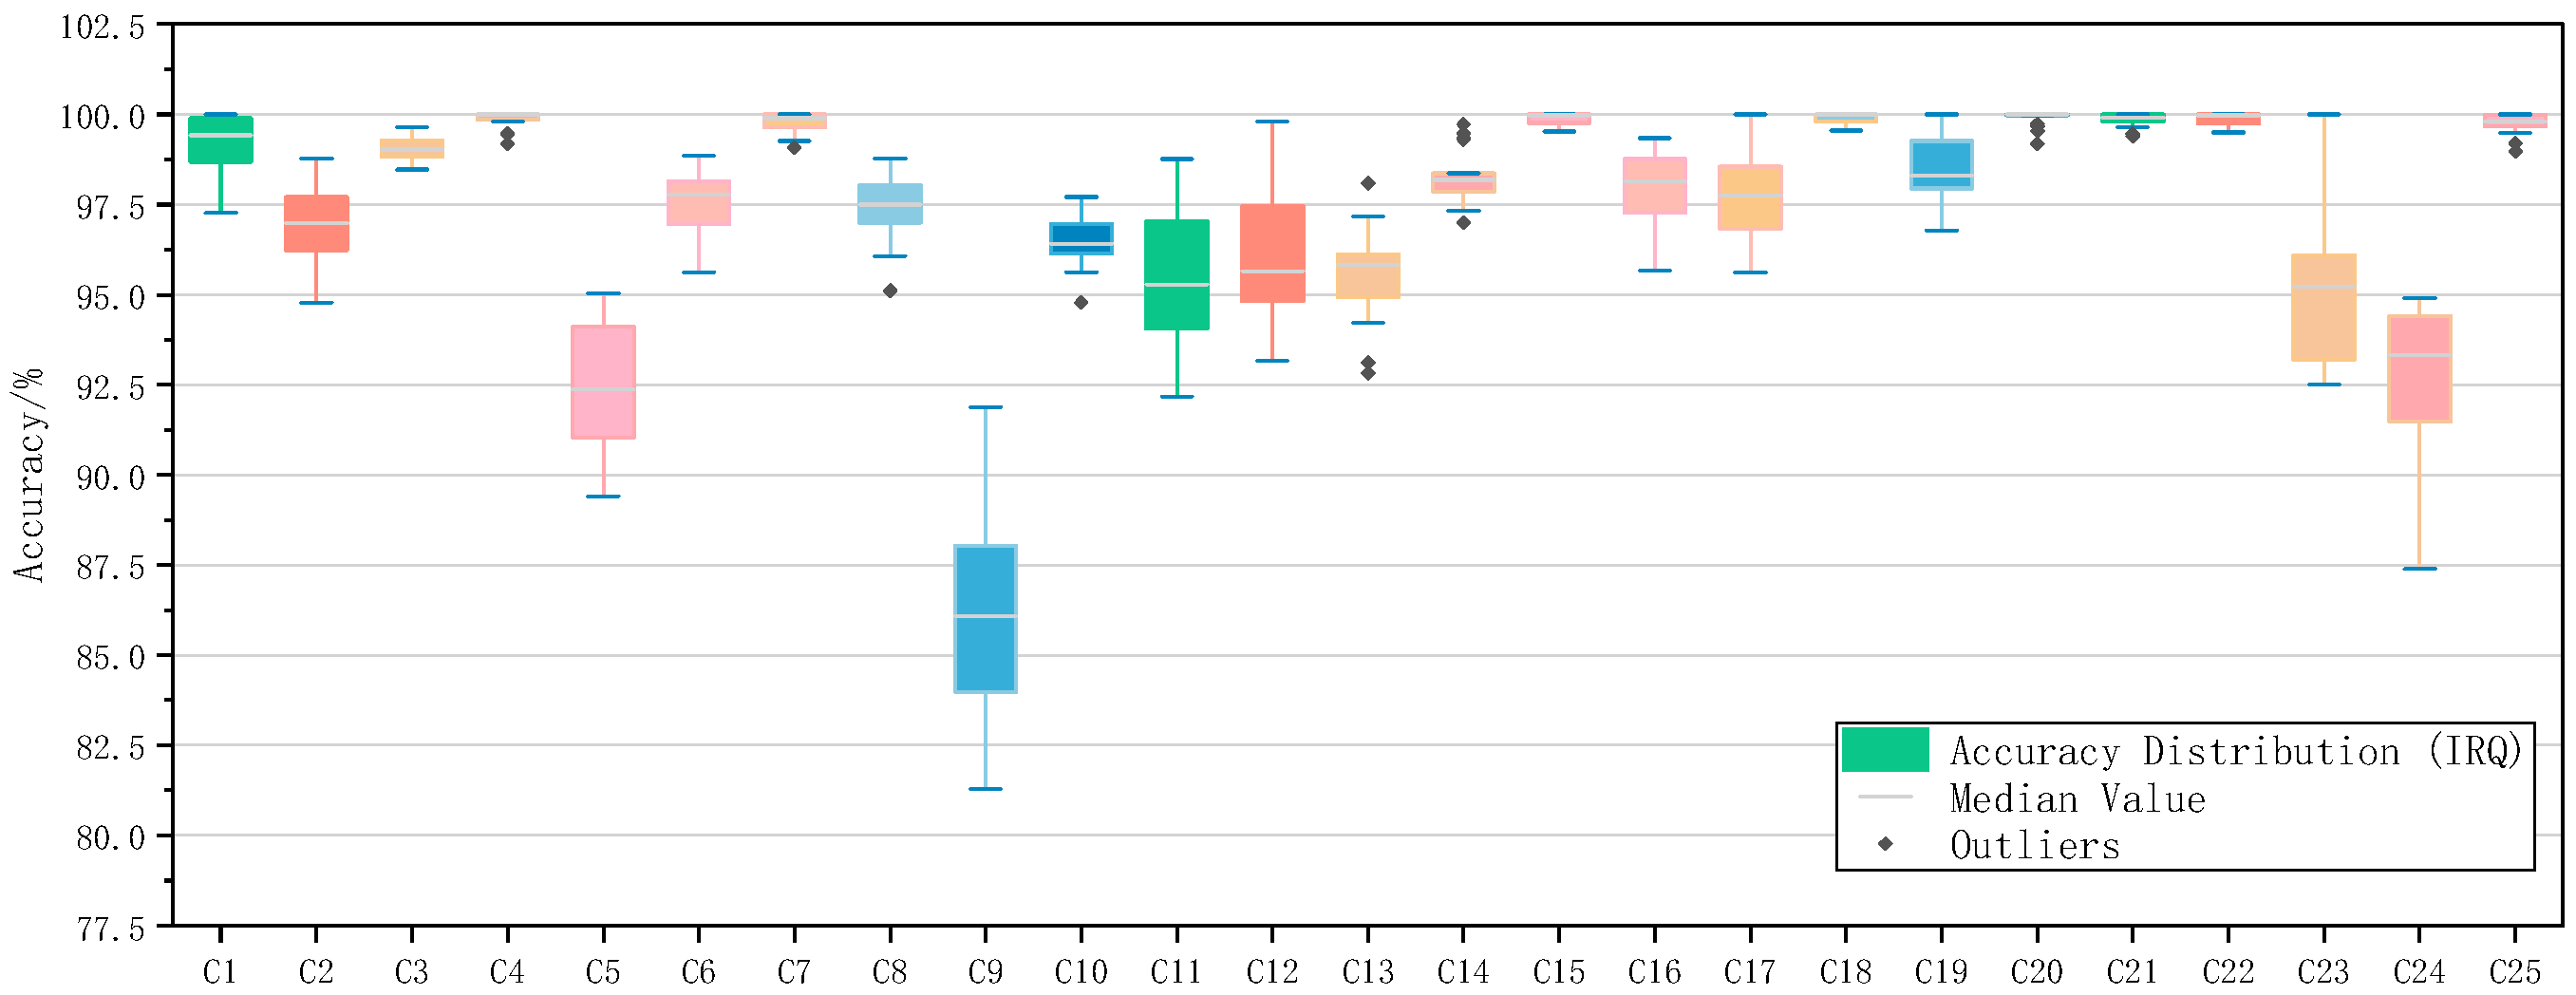
The recognition performance of AD-PDAF-Net for the 25 categories of power quality disturbances under the strong 20 dB noise condition was evaluated through 20 repeated experiments. The statistical results are presented in Table 8, and the distribution of per-category recognition accuracy is shown in the box plot of Figure 11.
Table 8.
Average Recognition Accuracy for Each Disturbance Category under 20 dB.
Figure 11.
Boxplot of recognition accuracy for each disturbance category (20 dB).
The analysis reveals differences in recognition performance and stability across categories. Categories such as C4, C15, C18, C20, C21, and C22 all achieved average recognition accuracies above 99.85%. Their box plots indicate a median of 100% with compact interquartile ranges, demonstrating superior and stable performance. In contrast, categories C9, C5, and C24 exhibited relatively lower average accuracies (86.13%, 92.49%, and 92.85%, respectively). Their box plots show longer boxes or skewness, suggesting room for improvement in recognition stability. Among these, category C9 had the largest standard deviation (2.67%), while C15 had the smallest (0.11%).
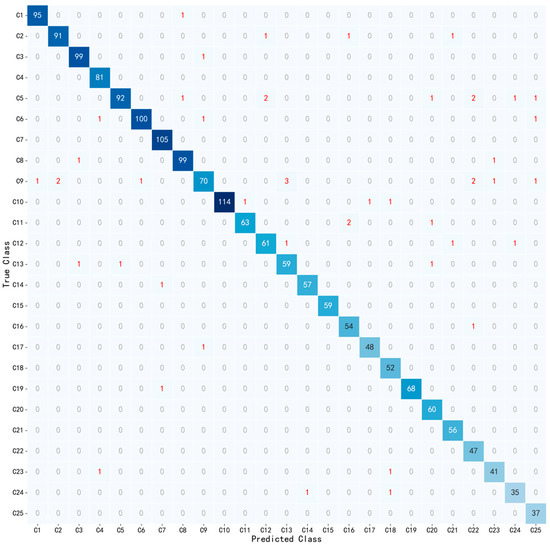
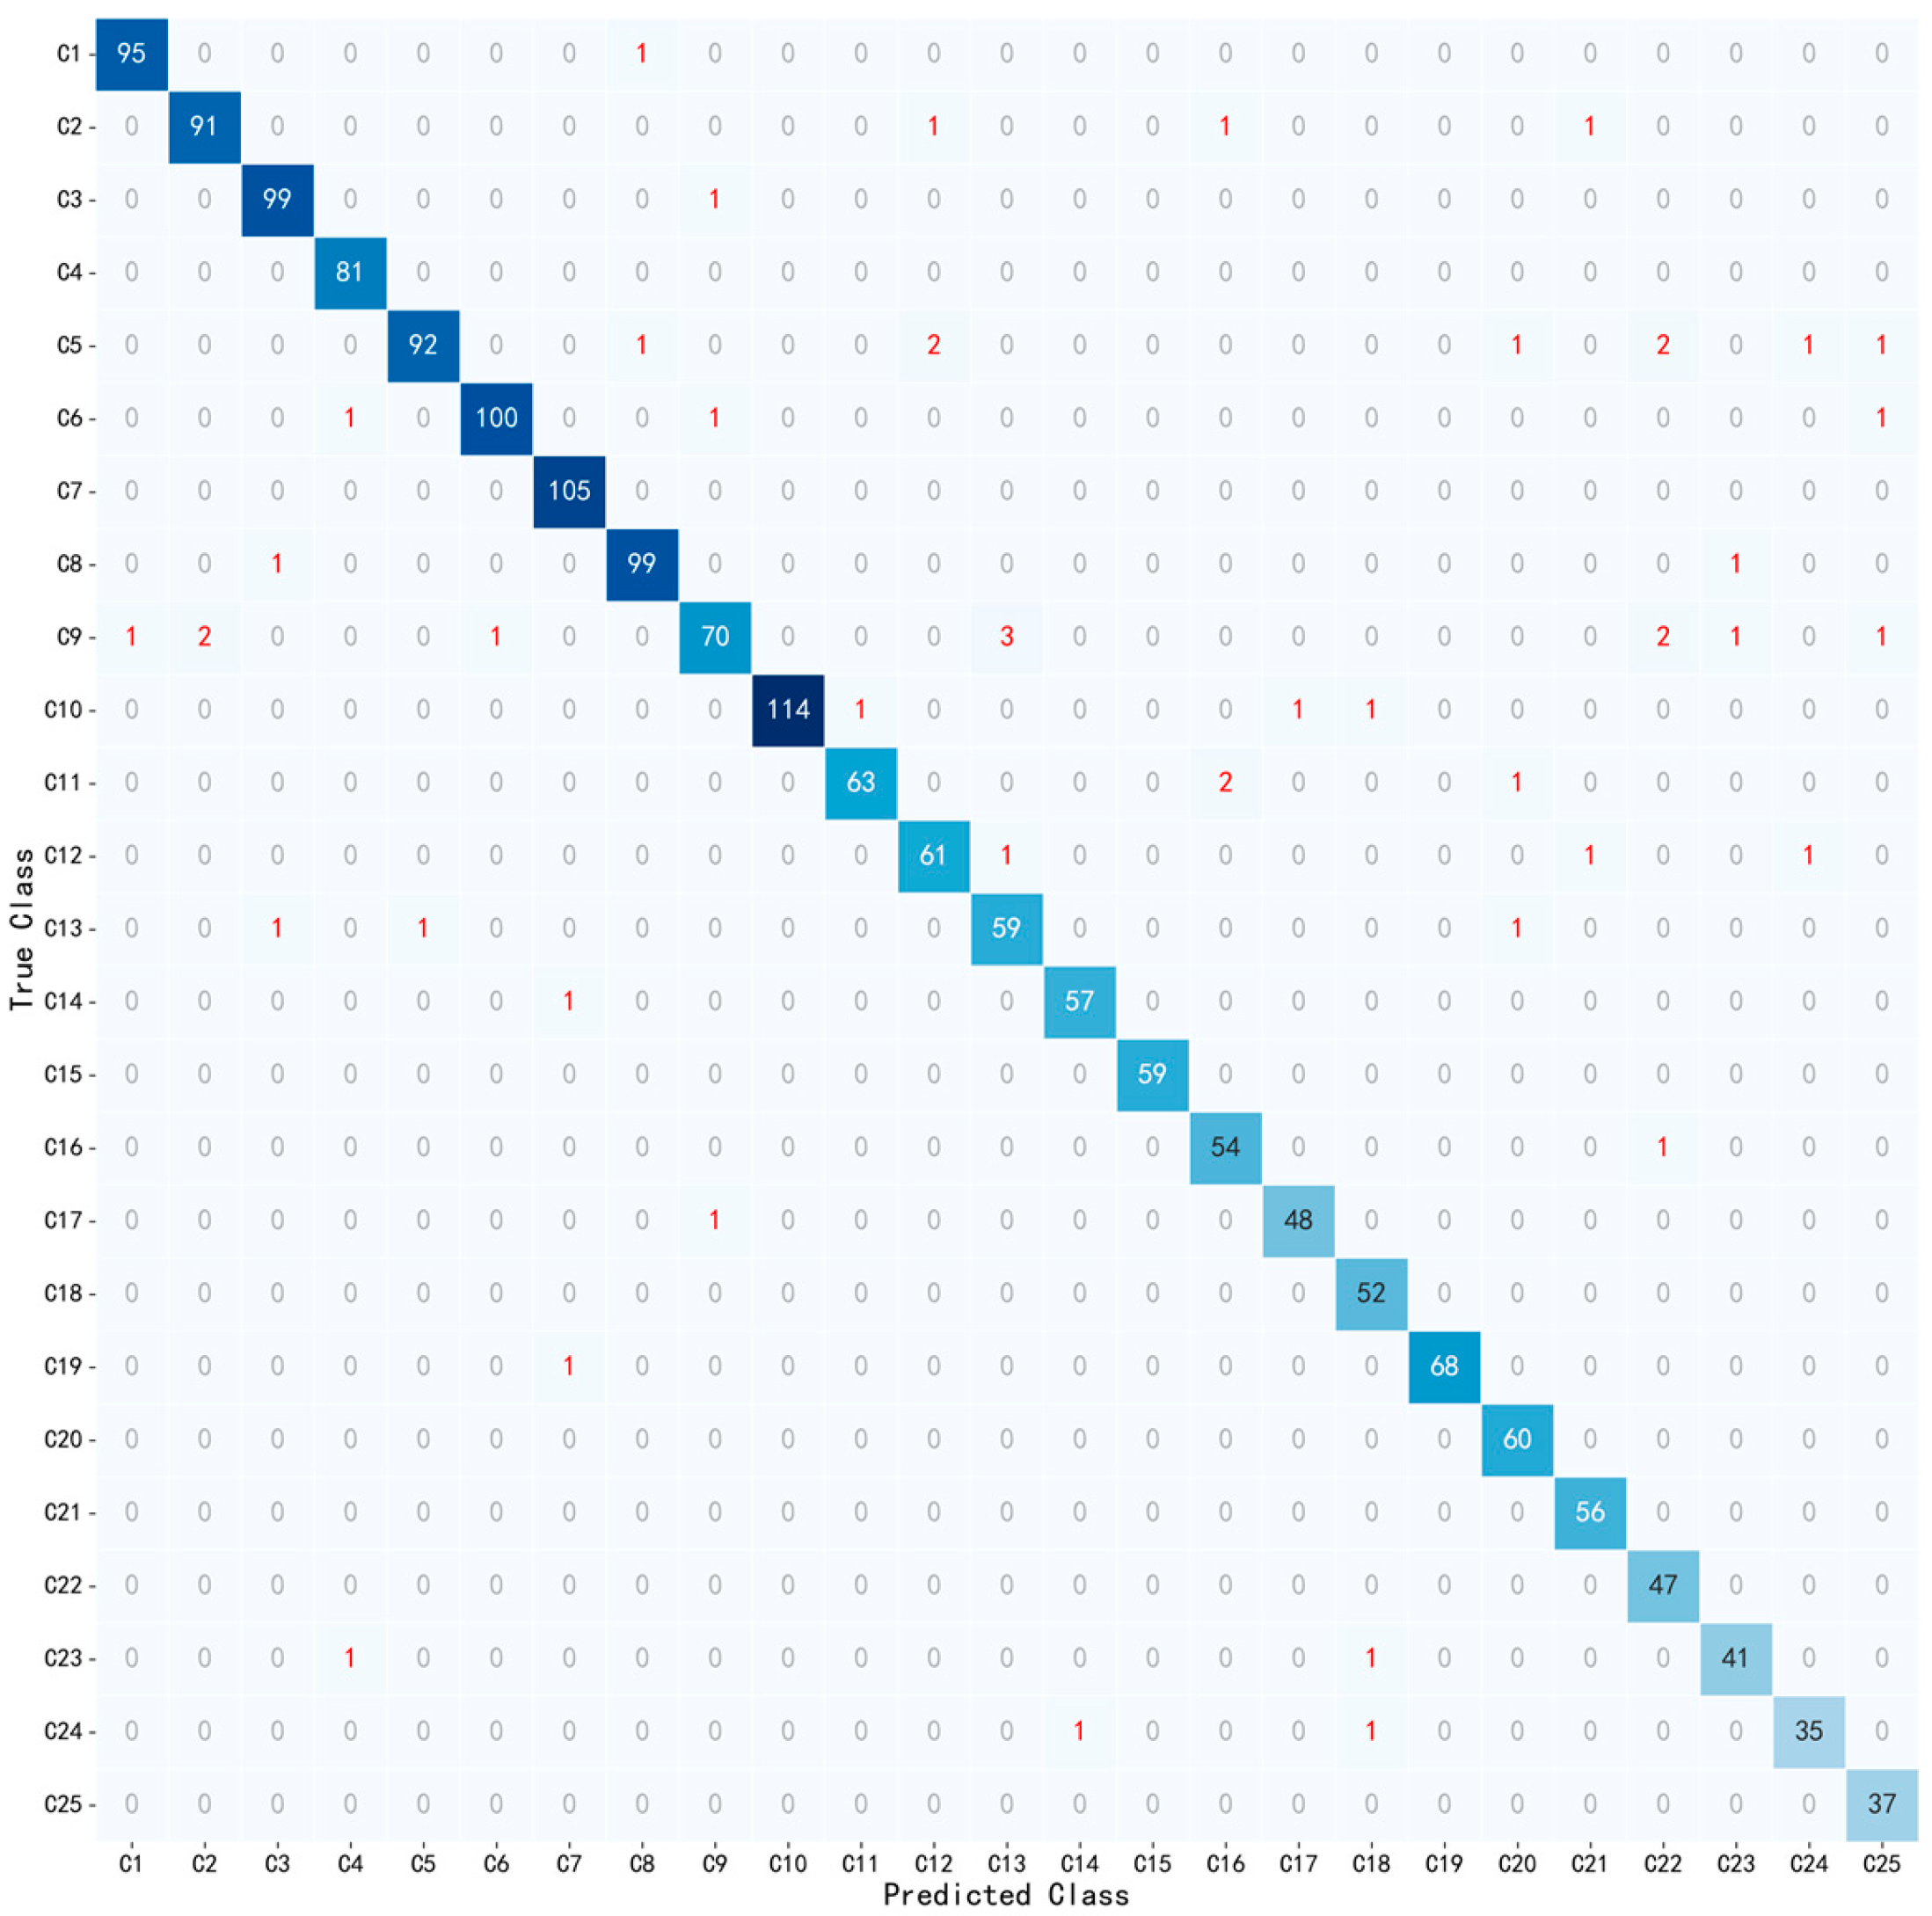
To further elucidate specific misclassification patterns, the confusion matrix under the same noise condition is provided in Figure 12. An analysis of the error distribution for the lower-performing categories is as follows: For category C5 (Recall: 92.00%), misclassifications were relatively dispersed, primarily to C12 and C22 (each constituting 25% of its total errors), with the remainder distributed among C8, C20, C24, and C25. For category C9 (Recall: 86.42%), errors were more concentrated, predominantly to C13 (accounting for 27.3% of its total errors), followed by C2 and C22 (each 18.2%). Notably, no mutual misclassification occurred between C5 and C9. Category C24 (Recall: 94.59%) showed good recognition performance, with its only two misclassifications directed to C14 and C18, respectively.
Figure 12.
Classification confusion matrix under 20 dB.
To ensure a more rigorous evaluation of how random signal-to-noise ratio (SNR) assignment affects model stability, we conducted 20 independent evaluations using the fully trained AD-PDAF-Net model on a mixed-noise test set. For each evaluation, a different random seed was used to assign an SNR, randomly selected from {20 dB, 30 dB, 40 dB}, to each test sample, and the recognition accuracy for the 25 perturbation categories was recorded, from which the model’s average recognition accuracy for that run was calculated. Based on the average recognition accuracy obtained across the 20 evaluations, we then computed the overall mean, which is the final reported average recognition accuracy, along with the standard deviation. The statistical results show a mean average recognition accuracy of 98.78% across the 20 runs, with a standard deviation of 0.321%, a minimum of 98.14%, and a maximum of 99.14%. To clearly illustrate the stability of recognition for each category, we recorded the per-category average recognition accuracy over the 20 evaluations and plotted box plots to show their distributions. Detailed experimental data are provided in Table A2 and Figure A1 in Appendix B. These results indicate that AD-PDAF-Net exhibits excellent stability under random SNR assignment, a robustness that stems from the model’s inherent noise resistance rather than any coincidentally favorable noise distribution.
In summary, the proposed method achieves high-precision and stable recognition for the vast majority of PQD categories under both severe 20 dB noise and mixed-noise scenarios. Although there remains room for improvement in the recognition performance of complex categories such as voltage notch (C9) and flicker (C5), the overall experimental results fully demonstrate the model’s exceptional performance and practical potential for handling challenging grid environments.
4. Discussion
In this chapter, we analyze the internal mechanisms, performance advantages, and operational boundaries of the AD-PDAF-Net model using the experimental results established in Chapter 3. The discussion confirms that the observed performance gains are a direct result of a core design that successfully addresses the three primary challenges identified in the Introduction.
4.1. Embedded Adaptive Denoising Mechanism
The adaptive soft thresholding denoising layer (ASDL) provides an integrated solution to the absence of built-in noise suppression in conventional architectures. Ablation results in Table 6 confirm that the ASDL is essential for maintaining a high accuracy of 97.26% under strong 20 dB noise. By learning channel-specific thresholds, this layer zeros out components with magnitudes below the threshold at the feature map level while contracting the valid signal, achieving progressive filtering that works in tandem with feature extraction. This strategy of integrating denoising into weight optimization avoids the disconnect between independent preprocessing and the training objective, which significantly enhances the inherent robustness of the model under low signal-to-noise ratio (SNR) conditions. However, performance for disturbances such as flicker (C5, 92.49%) and voltage notch (C9, 86.13%) remains relatively limited as noted in Section 3.5. This suggests that threshold estimation based on global average pooling may lack sufficient sensitivity to energy dispersed or slowly varying features, potentially suppressing useful low-frequency information. Future research could explore threshold generation mechanisms that utilize multi-scale analysis or frequency domain awareness to improve the separation of such weak-feature disturbances.
4.2. Feature Cooperation Mechanism of the PDAF Module
The parallel dual attention fusion (PDAF) module decouples and complements time domain and frequency domain features through its structural design to address the limitations of single mechanism feature refinement. Ablation results in Table 7 show that its performance surpasses that of single attention or serial structures. The channel attention (CA) sub-module performs global recalibration of feature channels to enhance discriminative frequency bands, while the multi-scale self-attention (MSA) sub-module focuses on key temporal segments. Processing these paths in parallel and fusing them via learnable weights allows the network to adaptively adjust its feature reliance based on the physical characteristics of the signal. The dynamic fusion weights eventually stabilize with a bias toward the MSA output at approximately 0.65, indicating that precise temporal context modeling is more critical than channel weight optimization alone in strong noise. Feature visualizations demonstrate how this module forms differentiated enhancement patterns for various disturbances, validating its cooperative optimization mechanism.
4.3. Balanced Design for Efficiency and Performance
AD-PDAF-Net achieves a parameter count of 0.36 M and a computational cost of 1.50 GFLOPS, significantly lower than GAF-ResNet18 (1125.51 GFLOPS, 11.19 M), ResNet-LSTM (8.55 GFLOPS, 1.44 M), and DCNN (4.04 GFLOPS, 1.16 M), demonstrating a clear advantage in terms of lightweight design. In terms of performance, the model achieves an accuracy of 97.26% under strong 20 dB noise, outperforming comparative methods such as Dual-ResNet (96.65%) and TC + ResNet18 (92.92%), while reaching 98.78% under mixed-noise conditions, confirming its robustness. Ablation studies show that the ASDL contributes an accuracy improvement of approximately 4.7 percentage points under 20 dB strong noise, while introducing only a small number of additional convolutional parameters and activation functions, reflecting a design philosophy that achieves significant performance gains with minimal structural overhead. In summary, AD-PDAF-Net achieves leading classification accuracy and robustness under both strong noise and mixed noise environments with extremely low computational cost and model size, striking an effective balance between performance and efficiency.
4.4. Limitations and Future Work
Despite the promising results, several limitations of this study should be acknowledged. First, the recognition accuracy for disturbances with subtle features, such as voltage notches (C9) and flickers (C5), remains suboptimal and warrants further refinement. Second, as the experimental validation was primarily conducted using simulated Gaussian white noise and mixed-noise scenarios, the model’s generalization capability in the face of non-Gaussian or non-stationary electromagnetic interference in industrial environments remains to be verified.
Consequently, future research will focus on integrating multi-modal information or multi-scale analysis to enhance the capture of weak-signal characteristics. Furthermore, we aim to collaborate with power grid utilities to establish a benchmark dataset based on field recordings. This will facilitate a comprehensive assessment of the model’s long-term stability and reliability under the complexities of real-world power system operations.
5. Conclusions
To achieve highly robust and efficient PQD identification in complex industrial noise environments, the AD-PDAF-Net model is proposed. Experimental results demonstrate its leading classification accuracy and stability even under severe noise conditions.
The core contribution of this work extends beyond individual module innovation by proposing a deep learning design framework for the joint optimization of noise suppression, feature refinement, and efficiency constraints. This framework transforms noise suppression from an independent preprocessing step into a process that works in tandem with feature learning via the embedded adaptive denoising mechanism. It achieves adaptive feature cooperation across time and frequency domains through the parallel dual attention fusion mechanism. Finally, structural lightweighting ensures efficient deployment without compromising performance. These three aspects are integrated to address the trade-offs between noise robustness, feature discriminability, and computational efficiency.
More importantly, this framework provides a scalable methodology for time series signal analysis in environments characterized by strong noise, non-stationary interference, and limited resources. Its design philosophy of embedded processing, parallel cooperation, and lightweight constraints is transferable to other industrial intelligent sensing domains that require the extraction of weak-features from complex backgrounds, such as mechanical fault diagnosis, speech enhancement, and biomedical signal analysis, demonstrating significant potential for broad application.
Author Contributions
Conceptualization, T.H.; methodology, Y.Z. and T.H.; software, T.H.; validation, Y.Z.; formal analysis, Y.Z. and T.H.; investigation, Y.Z. and T.H.; resources, Y.Z.; data curation, Y.Z. and T.H.; writing—original draft preparation, T.H.; writing—review and editing, Y.Z.; visualization, Y.Z. and T.H.; supervision, Y.Z.; project administration, Y.Z. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by the Liaoning Province Department of Science and Technology, grant number 2024-MSLH-197.
Data Availability Statement
Data are contained within the article.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| ASDL | Adaptive Soft-thresholding Denoising Layer |
| BiLSTM | Bidirectional Long Short-Term Memory |
| CA | Channel Attention |
| MSA | Multi-scale Self-Attention |
| PDAF | Parallel Dual-Attention Adaptive Fusion |
| PQD | Power Quality Disturbance |
| SNR | Signal-to-Noise Ratio |
| AD-PDAF-Net | Adaptive Denoising and Parallel Dual-Attention Fusion Network |
| t-SNE | t-Distributed Stochastic Neighbor Embedding |
Appendix A
Table A1.
Mathematical Models and Boundary Conditions for 25 PQDs.
Appendix B
Figure A1.
Boxplot of average recognition accuracy for each disturbance category under mixed-noise conditions.
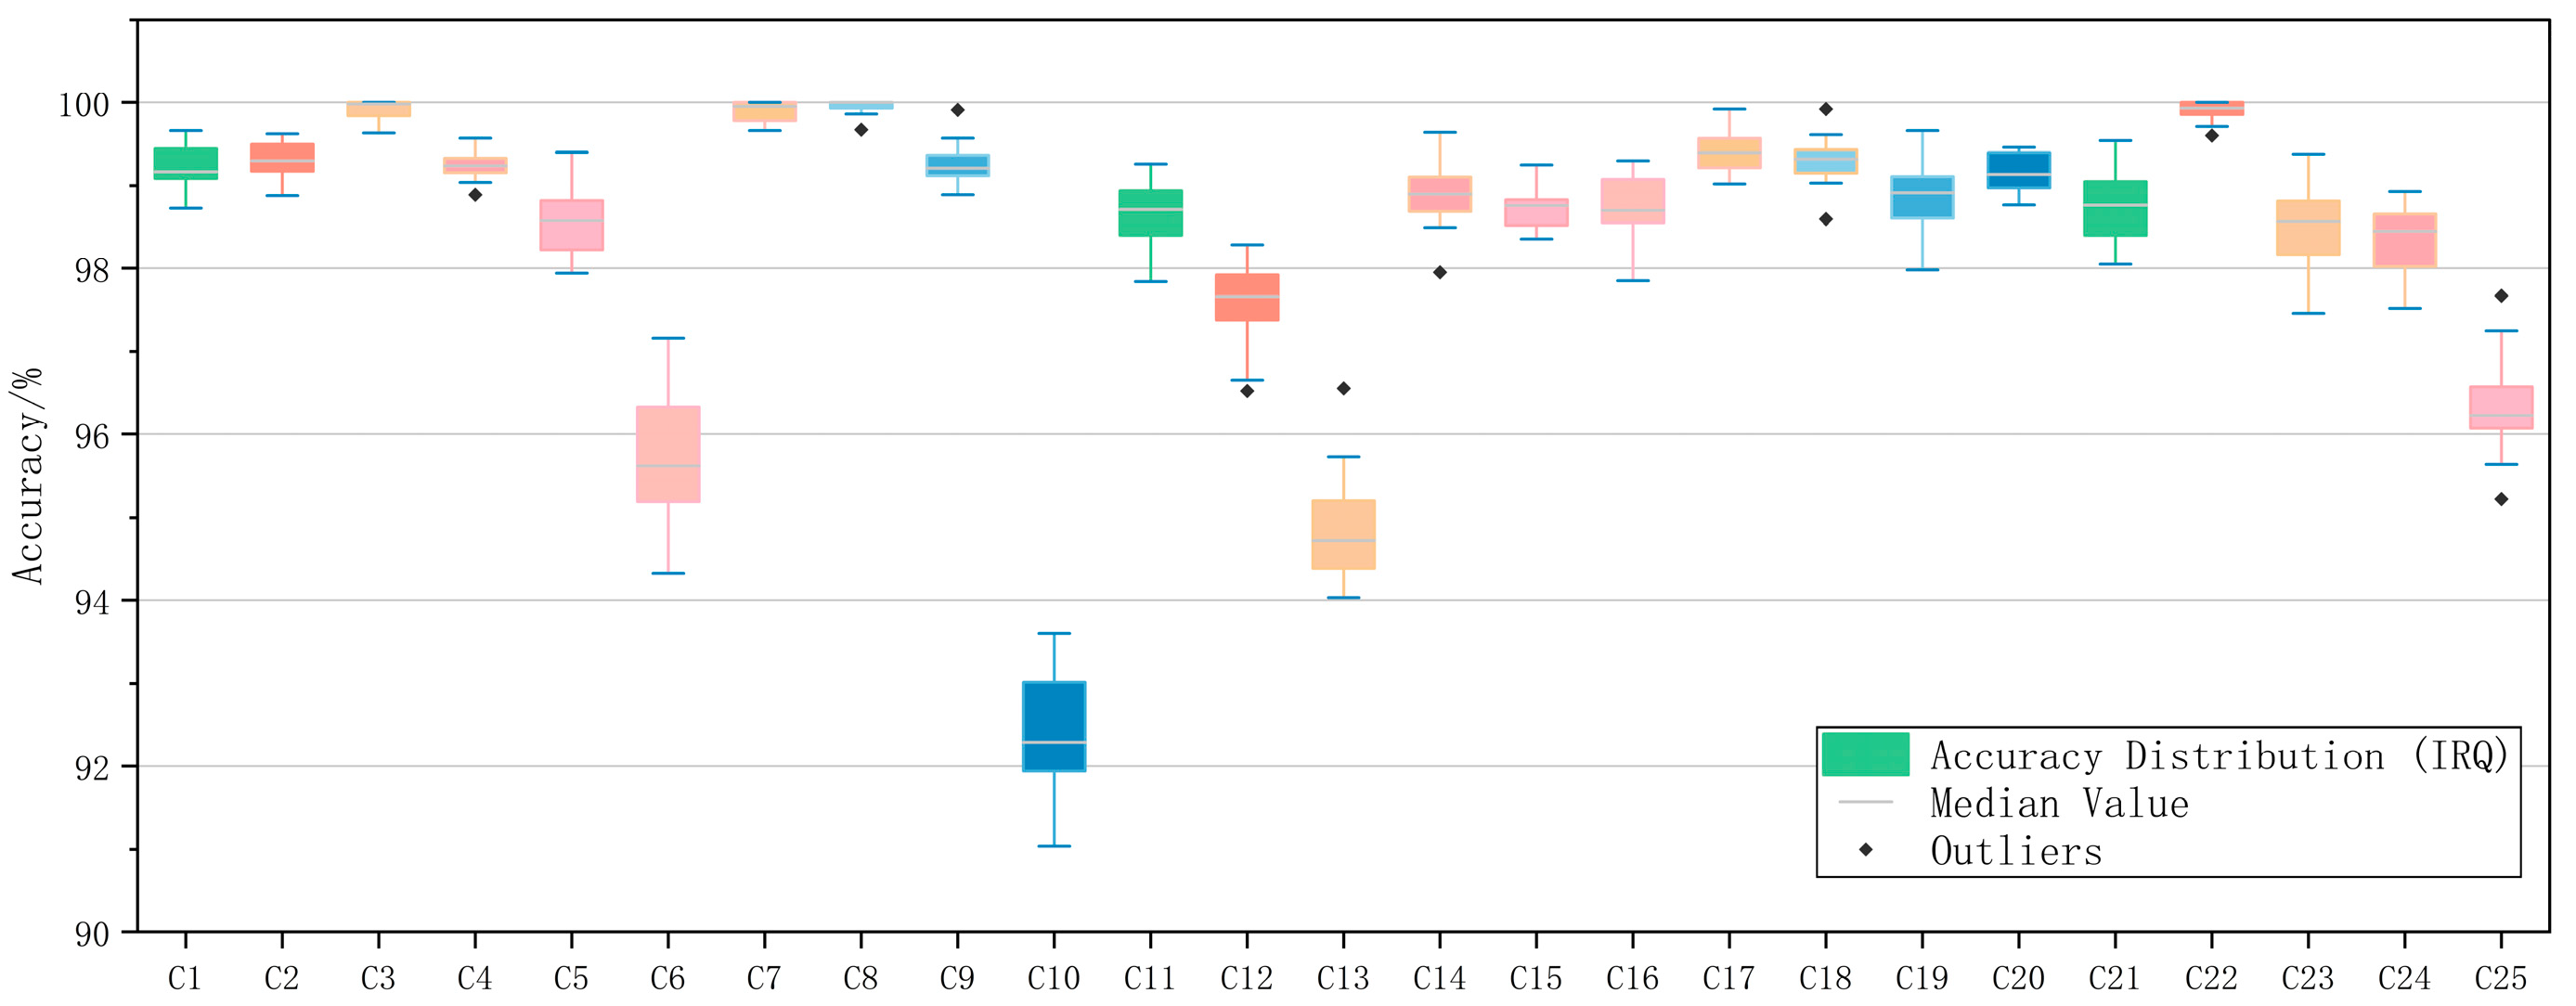
Table A2.
Average recognition accuracy for each disturbance category under mixed-noise conditions.
References
- Yang, H.G.; Liu, J.Y.; Xiao, X.Y. Issues and technology assessment on power quality Part 6: Advance of power quality control technology. Electr. Power Autom. Equip. 2004, 24, 1–5. [Google Scholar]
- Zhong, Q.; Huang, W.; Tao, S.; Xiao, X. Survey on assessment of power quality cost in Shanghai China. In Proceedings of the 2014 IEEE PES General Meeting | Conference & Exposition, National Harbor, MD, USA, 27–31 July 2014. [Google Scholar]
- Targosz, R.; Manson, J. Pan-European Power Quality Survey: A study of the impact of power quality on electrical energy critical industrial sectors. In Proceedings of the International Conference on Electrical Power Quality and Utilisation, Barcelona, Spain, 9–11 October 2007. [Google Scholar]
- Huang, J.M.; Qin, G.; Li, X.M. Classification for Hybrid Power Quality Disturbance Based on STFT and Its Spectral Kurtosis. Power Syst. Technol. 2016, 40, 3184–3191. [Google Scholar]
- Zhang, Y.; Ji, T.Y.; Li, M.S.; Wu, Q.H. Identification of Power Disturbances Using Generalized Morphological Open-Closing and Close-Opening Undecimated Wavelet. IEEE Trans. Ind. Electron. 2016, 63, 2330–2339. [Google Scholar] [CrossRef] [Scilit]
- Li, J.W.; Qin, G.; Li, Y.G.; Dong, J. Feature Extraction Based on S-transform of Blackman Window and Window Ratio in Power Quality Disturbances. High Volt. Eng. 2020, 46, 2769–2779. [Google Scholar]
- Biswal, B.; Biswal, M.; Mishra, S.; Jalaja, R. Automatic classification of power quality events using balanced neural tree. IEEE Trans. Ind. Electron. 2013, 61, 521–530. [Google Scholar] [CrossRef] [Scilit]
- Khetarpal, P.; Nagpal, N.; Alhelou, H.H.; Siano, P.; Al-Numay, M. Noisy and non-stationary power quality disturbance classification based on adaptive segmentation empirical wavelet transform and support vector machine. Comput. Electr. Eng. 2024, 118, 109346. [Google Scholar] [CrossRef] [Scilit]
- Wang, H.H.; Wang, P.; Liu, T. Power Quality Disturbance Classification Using the S-Transform and Probabilistic Neural Network. Energies 2017, 10, 107. [Google Scholar] [CrossRef] [Scilit]
- Liu, Z.; Cui, Y.; Li, W. A Classification Method for Complex Power Quality Disturbances Using EEMD and Rank Wavelet SVM. IEEE Trans. Smart Grid 2017, 6, 1678–1685. [Google Scholar] [CrossRef] [Scilit]
- Huang, N.T.; Peng, H.; Cai, G.W.; Xu, D. Feature Selection and Optimal Decision Tree Construction of Complex Power Quality Disturbances. Proc. CSEE 2017, 37, 776–786. [Google Scholar]
- Huang, N.T.; Zhao, W.G.; Cai, G.W.; Qi, J.; Chen, S.; Chen, Q. Efficient Recognition of Power Quality Disturbance of LightGBM Considering Data Transmission Rate Constraints of IoT. Proc. CSEE 2021, 41, 5189–5201. [Google Scholar]
- Jana, C.; Banerjee, S.; Maur, S.; Dalai, S. Customized CNN based classification of power system disturbances using recurrence plots. Electr. Power Syst. Res. 2025, 241, 111370. [Google Scholar] [CrossRef] [Scilit]
- Salles, R.S.; Ribeiro, P.F. The use of deep learning and 2-D wavelet scalograms for power quality disturbances classification. Electr. Power Syst. Res. 2023, 214, 108834. [Google Scholar] [CrossRef] [Scilit]
- Liao, T.; Wang, W.; Xing, Y. A method for disturbance identification in power quality based on cross-attention fusion of temporal and spatial features. Electr. Power Syst. Res. 2024, 234, 110560. [Google Scholar] [CrossRef] [Scilit]
- Liu, Y.; Jin, T.; Mohamed, M.A. A novel dual-attention optimization model for points classification of power quality disturbances. Appl. Energy 2023, 339, 121011. [Google Scholar] [CrossRef] [Scilit]
- Meng, H.Y.; Zhang, J.L.; Cai, Z.L.; Li, C. Research on DC Microgrid Fault Diagnosis Based on CNN-BiLSTM-Attention. Proc. CSEE 2025, 45, 1369–1381. [Google Scholar]
- Bai, H.; Yao, R.; Zhang, W.; Zhong, Z.; Zou, H. Power Quality Disturbance Classification Strategy Based on Fast S-Transform and an Improved CNN-LSTM Hybrid Model. Processes 2025, 13, 743. [Google Scholar] [CrossRef] [Scilit]
- IEEE Standard 1159-2019; IEEE Recommended Practice for Monitoring Electric Power Quality. IEEE: New York, NY, USA, 2019.
- Xi, X.; Xing, C.; Qin, R.; Guo, C.; Zhou, X. Power Quality Disturbance Identification Method Based on Deep Convolutional Denoising Network. South. Power Syst. Technol. 2022, 16, 118–125. [Google Scholar]
- Peruman, P.M.; Ayyar, K. Power quality disturbance identification using hybrid deep learning in renewable energy systems. Sci. Rep. 2025, 15, 37. [Google Scholar] [CrossRef] [Scilit]
- Liu, Y.L.; Cui, X.Y.; Yuan, D.; Jin, T. Research on Multi-level Attention Mechanism Optimized Method for Point Classification and Time Interval Identification of Power Quality Disturbances. Proc. CSEE 2024, 44, 4298–4311. [Google Scholar]
- Gong, Z.; Zou, Y.; Jin, T.; Liu, Y.; Lan, M.; Liu, Z. Classification Method of Power Quality Disturbances Based on Optimized Parallel Model of Features Merging. Proc. CSEE 2023, 43, 1017–1027. [Google Scholar]
- Ge, Y.; Li, Z.; Zhou, W.; Guo, X.; Peng, Z.; Dong, F. A New Precise Power Quality Disturbance Identification Framework Based on Two-Dimensional Characterization Feature Enhancement and Deep Learning. Processes 2025, 13, 675. [Google Scholar] [CrossRef] [Scilit]
- Wang, J.; Wang, Z.; Zhang, D. Power Quality Disturbance Classification Based on Recursive Graph and Pre-Trained Transfer Learning. South. Power Syst. Technol. 2025, 19, 48–56+114. [Google Scholar]
- Lan, M.Y.; Liu, Y.L.; Jin, T. An Improved Recognition Method Based on Visual Trajectory Circle and ResnetN18 for Complex Power Quality Disturbances. Proc. CSEE 2022, 42, 6274–6286. [Google Scholar]
- Song, J.; Wu, J.; Wang, X.; Duan, Z.; Wang, X.; Lu, S. Accurate classification of power quality disturbance based on 3D visualized spiral curve and hybrid ER-MVCNN model. Measurement 2024, 231, 114654. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.