Journal Description
Computation
Computation
is a peer-reviewed journal of computational science and engineering published monthly online by MDPI.
- Open Access— free for readers, with article processing charges (APC) paid by authors or their institutions.
- High Visibility: indexed within Scopus, ESCI (Web of Science), CAPlus / SciFinder, Inspec, dblp, and other databases.
- Journal Rank: JCR - Q2 (Mathematics, Interdisciplinary Applications) / CiteScore - Q1 (Applied Mathematics)
- Rapid Publication: manuscripts are peer-reviewed and a first decision is provided to authors approximately 13.6 days after submission; acceptance to publication is undertaken in 5.6 days (median values for papers published in this journal in the first half of 2026).
- Recognition of Reviewers: Reviewers whose reports are timely and of high quality receive an APC discount voucher for a future publication in an MDPI journal. Become a reviewer.
- Journal Cluster of Mathematics and Its Applications: AppliedMath, Axioms, Computation, Fractal and Fractional, Geometry, International Journal of Topology, Logics, Mathematics and Symmetry.
Impact Factor:
2.6 (2025);
5-Year Impact Factor:
2.1 (2025)
Latest Articles
A Mathematical Model of Opinion Dynamics with Application to Vaccine Denial
Computation 2026, 14(9), 219; https://doi.org/10.3390/computation14090219 - 16 Sep 2026
Abstract
Public health outcomes can be heavily influenced by the landscape of public opinion; hence, it is important to understand how that landscape changes over time. For one, opinions on public health issues are responsive to official pronouncements, whether from the governmental or professional
[...] Read more.
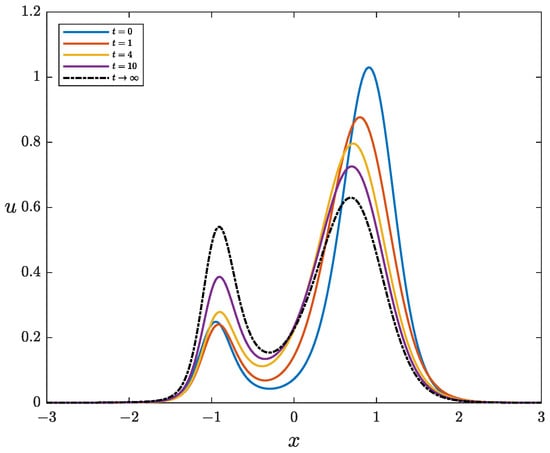
Public health outcomes can be heavily influenced by the landscape of public opinion; hence, it is important to understand how that landscape changes over time. For one, opinions on public health issues are responsive to official pronouncements, whether from the governmental or professional medical establishments. Additionally, in today’s world of high speed communication, opinion can also be highly responsive to the broadcast opinions of “influencers” whose large numbers of followers assure them of a broad reach. To understand the opinion landscape in a general sense, we develop an ordinary differential equation model for opinion change that is based primarily on attraction to prominent sources whose opinions are independent of the opinions of others. The individual opinion change model is then used to develop a Fokker–Planck-type partial differential equation model for the overall opinion landscape. This model is shown to have a stable equilibrium solution, and the dependence of the equilibrium solution on key model parameters is illustrated with examples based on opinion regarding vaccination. Eigenvalues and eigenfunctions for the associated Sturm–Liouville problem are determined numerically by two methods, one by using numerical solutions of the partial differential equation and the other by applying a shooting method directly to the eigenvalue problem.
Full article
(This article belongs to the Section Computational Social Science)
►
Show Figures
Open AccessArticle
COATWD: Cost-Optimized Adaptive Three-Way Decision for Cloud–Edge Task Orchestration
by
Jin Yang and Suchada Sitjongsataporn
Computation 2026, 14(9), 218; https://doi.org/10.3390/computation14090218 - 15 Sep 2026
Abstract
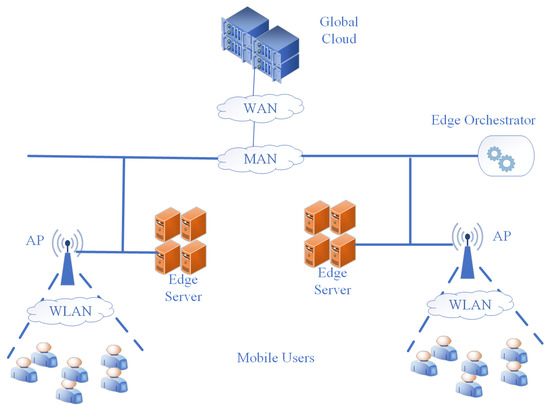
With the increasing number of end devices and the growing heterogeneity of application demands, task orchestration in dynamic cloud–edge environments faces challenges arising from network fluctuations, resource contention, and decision uncertainty. To address these challenges, this paper proposes a Cost-Optimized Adaptive Three-Way Decision
[...] Read more.
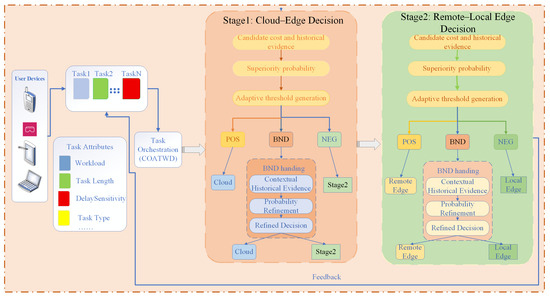
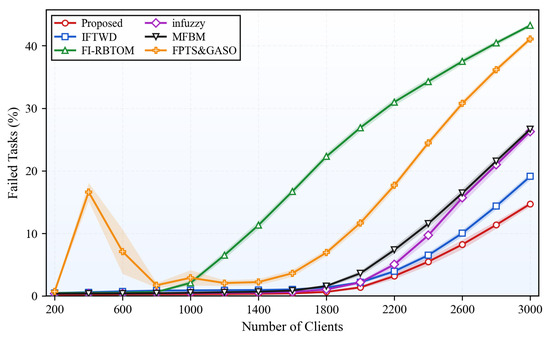
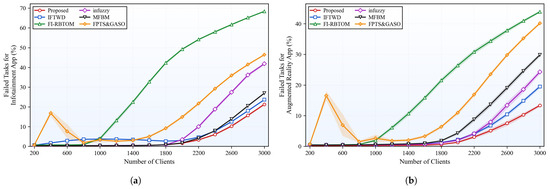
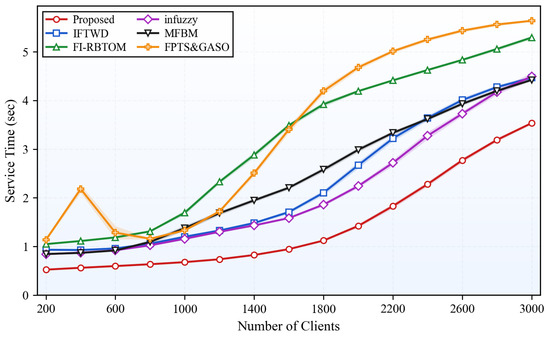
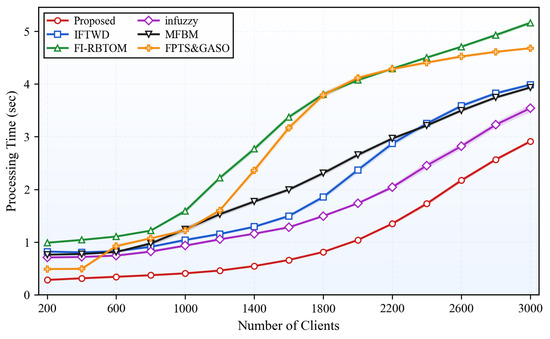
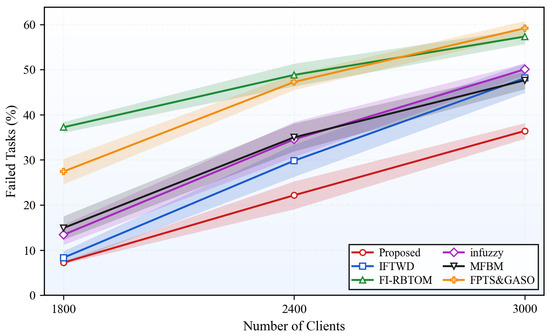
With the increasing number of end devices and the growing heterogeneity of application demands, task orchestration in dynamic cloud–edge environments faces challenges arising from network fluctuations, resource contention, and decision uncertainty. To address these challenges, this paper proposes a Cost-Optimized Adaptive Three-Way Decision (COATWD) method for cloud–edge task orchestration. Candidate execution costs for Local Edge, Remote Edge, and Cloud are evaluated by jointly considering network transmission, task queuing, task execution, and QoS constraints, while historical prediction residuals provide empirical evidence for estimating candidate-superiority probabilities. Based on the current task characteristics and candidate resource states, decision losses are dynamically constructed, and adaptive dual thresholds are generated according to the effectiveness of historical refinement, thereby partitioning candidate relations into positive, boundary, and negative regions. Candidate relations assigned to the boundary region are further refined by matching historical information to the task type, candidate execution role, and specific Edge host. Observed execution outcomes continuously update prediction residuals and task success and failure statistics, thereby forming a closed-loop, online, adaptive orchestration process. Experimental results obtained with EdgeCloudSim 4.0 show that COATWD effectively reduces the task failure rate, average service time, and average processing time under different device scales and application workloads.
Full article
(This article belongs to the Special Issue Big Data Analysis and Fuzzy Systems)
►▼
Show Figures

Figure 1
Open AccessArticle
Numerical Error Propagation in Contemporary Molecular Dynamics Simulations of Lithium Battery Components
by
Luis A. Selis, Mauricio P. Galvez-Legua and Jorge G. Butler-Blacker
Computation 2026, 14(9), 217; https://doi.org/10.3390/computation14090217 - 15 Sep 2026
Abstract
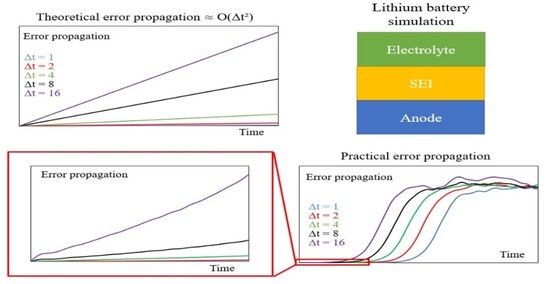
Molecular dynamics (MD) simulations rely on accurate numerical integration of the equations of motion, where the choice of the timestep (Δt) critically affects stability and precision. Rather than aiming to recover an exact atomic trajectory, second-order integrators, such as those implemented in LAMMPS
[...] Read more.
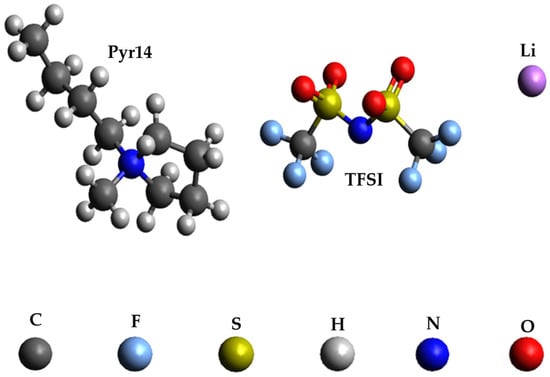
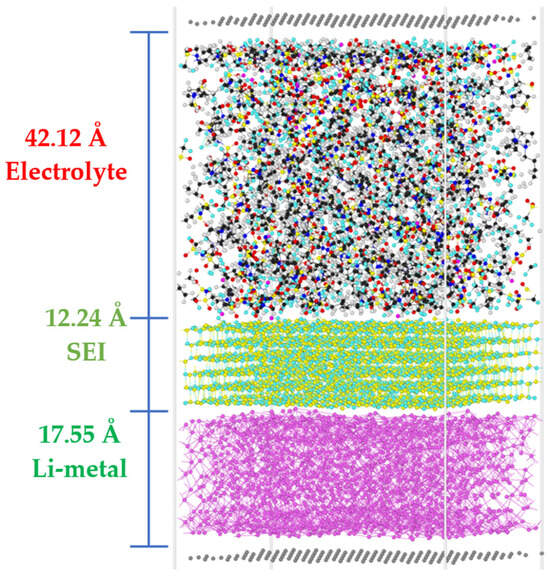
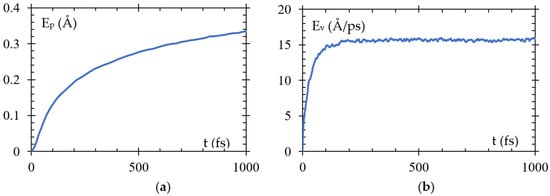
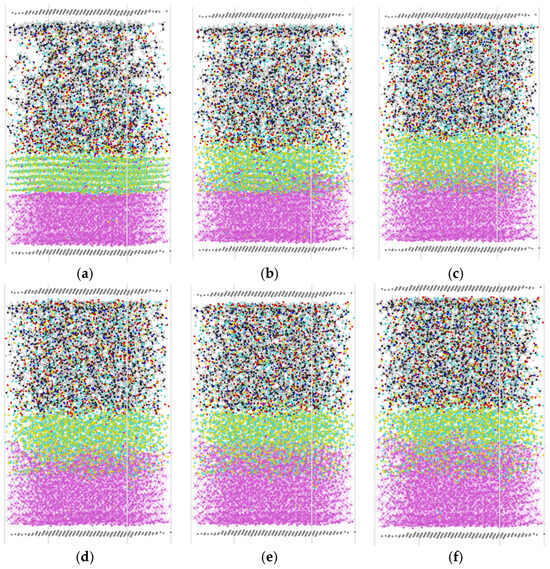
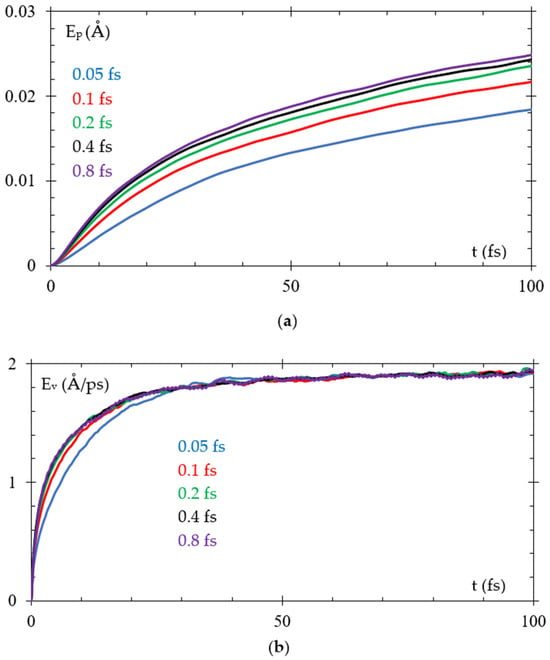
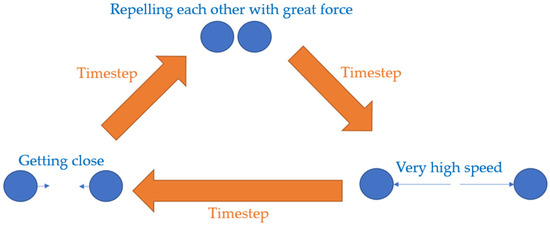
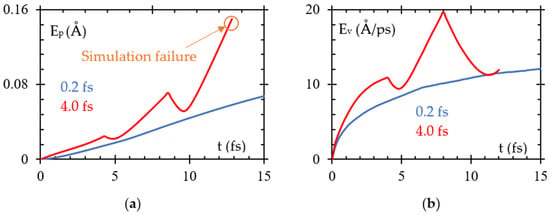
Molecular dynamics (MD) simulations rely on accurate numerical integration of the equations of motion, where the choice of the timestep (Δt) critically affects stability and precision. Rather than aiming to recover an exact atomic trajectory, second-order integrators, such as those implemented in LAMMPS with the Nosé–Hoover thermostat, yield a global error scaling as O(Δt2). However, practical results deviate from this ideal behavior. In this work, we systematically analyze the effect of Δt on the accuracy of MD simulations using a polarizable force field applied to battery-relevant systems. Different errors were quantified for a range of timesteps. We evaluate whether timestep-induced numerical deviations affect physically meaningful observables, including diffusion coefficients and radial distribution functions, and examine the role of different integration schemes in solid and liquid components. The results show that decreasing Δt beyond the stability threshold leads to only marginal improvements in accuracy while significantly increasing computational cost at medium and long timescales. Conversely, excessively large Δt values produce numerical instability and unphysical behavior. These findings indicate that the expected ideal error scaling does not directly translate into practical accuracy gains and highlight the need for balanced timestep selection based on physical robustness rather than trajectory convergence alone.
Full article
(This article belongs to the Special Issue Energy and Advanced Computing in the Age of Machine Learning: From Quantum to Grid)
►▼
Show Figures

Graphical abstract
Open AccessArticle
Stochastic Semantic Fields for Sentiment-Driven Models
by
Luca Di Persio
Computation 2026, 14(9), 216; https://doi.org/10.3390/computation14090216 - 14 Sep 2026
Abstract
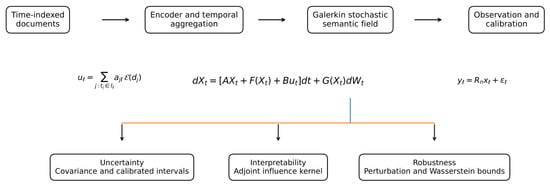
This article studies a time-dependent latent sentiment representation governed by a semilinear stochastic evolution equation on a separable Hilbert space. The objective is to derive uncertainty, interpretability, and robustness from one stochastic law. The mathematical analysis establishes covariance propagation and spectral uncertainty attribution,
[...] Read more.
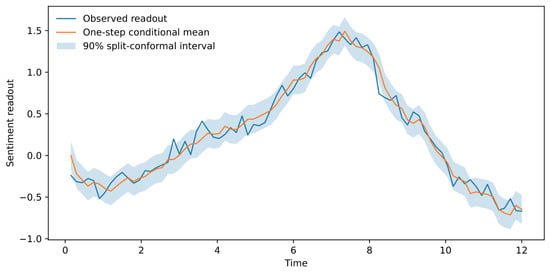
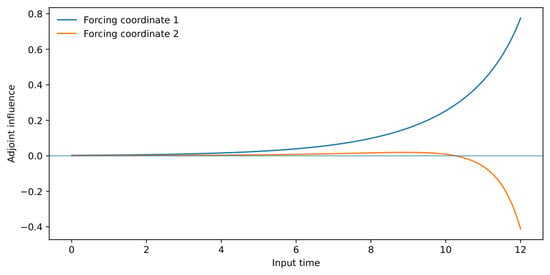
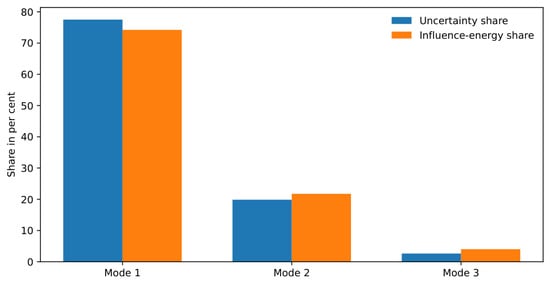
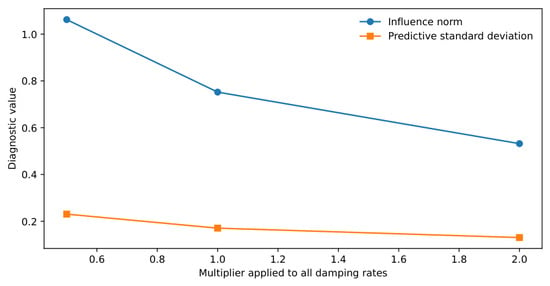
This article studies a time-dependent latent sentiment representation governed by a semilinear stochastic evolution equation on a separable Hilbert space. The objective is to derive uncertainty, interpretability, and robustness from one stochastic law. The mathematical analysis establishes covariance propagation and spectral uncertainty attribution, Fréchet differentiability of the forcing-to-state and forcing-to-readout maps with quadratic remainders, trace-norm differentiation of the covariance, and an adjoint influence kernel whose norm equals the exact worst-case displacement over an energy-bounded forcing ball in the linear regime. The dependence of the certificates on dissipativity, forecast horizon, noise geometry, and spectral truncation is made explicit. A Galerkin state-space reduction yields exact linear transitions, a likelihood-based calibration scheme, and structural identifiability conditions. A reproducible three-mode study verifies the covariance and duality identities, evaluates the sensitivity constants, and compares Gaussian with split-conformal predictive intervals under controlled synthetic conditions. The results provide a rigorous operator calculus and a tractable finite approximation. They establish internal mathematical and numerical validity without asserting a generalised superiority.
Full article
(This article belongs to the Special Issue Sentiment-Driven Modelling in Business, Economics, and Social Sciences)
►▼
Show Figures

Figure 1
Open AccessReview
From 2D Vision–Language Models to Volumetric Medical AI: Large Language Models and Foundation Models for 3D Medical Imaging
by
Roni Ramon-Gonen and Haya Engelstein
Computation 2026, 14(9), 215; https://doi.org/10.3390/computation14090215 - 13 Sep 2026
Abstract
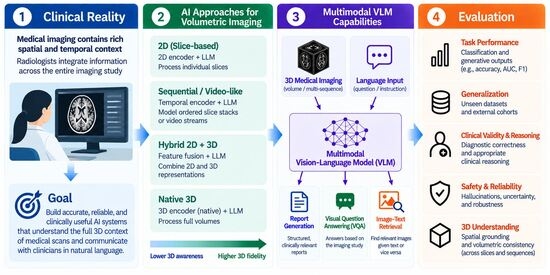
Multimodal large language models (MLLMs) and vision–language models (VLMs) have rapidly entered medicine, demonstrating promising performance in clinical reasoning, radiology report generation, and visual question answering (VQA). However, many current multimodal architectures and pretrained visual backbones remain fundamentally rooted in two-dimensional (2D) image
[...] Read more.
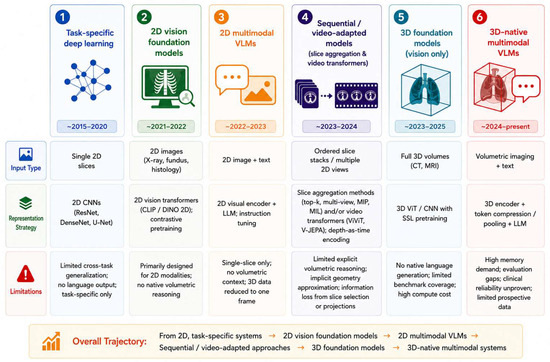
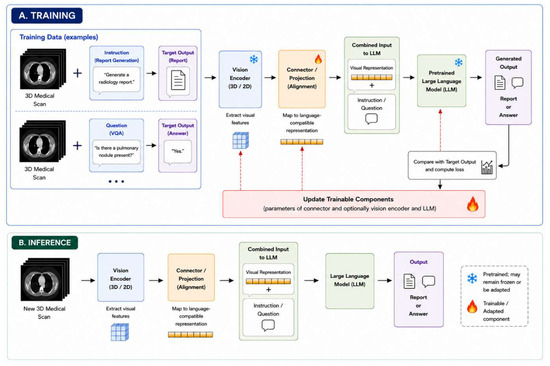
Multimodal large language models (MLLMs) and vision–language models (VLMs) have rapidly entered medicine, demonstrating promising performance in clinical reasoning, radiology report generation, and visual question answering (VQA). However, many current multimodal architectures and pretrained visual backbones remain fundamentally rooted in two-dimensional (2D) image processing, even though major clinical imaging modalities, including computed tomography (CT), magnetic resonance imaging (MRI), optical coherence tomography (OCT), and echocardiography, are inherently volumetric or temporal. This narrative review examines the transition from 2D vision–language systems to volumetric multimodal AI, tracing the evolution from 2D and slice- or projection-based approaches through sequential and video-like methods to three-dimensional (3D) vision foundation models and native 3D VLMs/MLLMs. We examine their representational and computational trade-offs, evaluation gaps, and clinically grounded benchmarks. Approaches differ substantially in how they represent and preserve 3D information. Slice- and projection-based methods offer computational efficiency but may discard spatial context, whereas sequential and native volumetric approaches increasingly model relationships across the full imaging study. Recent 3D foundation models and multimodal systems demonstrate the feasibility of reusable volumetric representations and language-enabled 3D image interpretation, but face barriers in computational cost, training-data scale, evaluation methodology, and clinical reliability. Only 53% of Med-Gemini-3D reports were judged clinically acceptable, and natural language processing (NLP) metrics such as BLEU and ROUGE correlate poorly with diagnostic correctness. True 3D multimodal medical intelligence remains in its early stages. Future progress requires efficient volumetric representation strategies, clinically grounded evaluation frameworks, standardized benchmarks, and robust cross-institution validation.
Full article
(This article belongs to the Special Issue Machine Learning and Large Language Models (LLMs) for Healthcare Analytics)
►▼
Show Figures

Graphical abstract
Open AccessArticle
Cross-National Statistical Analysis of Multi-Rotor Unmanned Aircraft Accidents: Causal Factors, Flight Phases, and Temporal Trends (2016–2022)
by
Fabio Garzia and Angelo Stella
Computation 2026, 14(9), 214; https://doi.org/10.3390/computation14090214 - 12 Sep 2026
Abstract
Multi-rotor unmanned aircraft systems (UAS) are now pervasive, yet quantitative evidence on how and why they fail remains fragmented across heterogeneous national reporting systems. This study analyses 319 multi-rotor UAS occurrences (2016–2022) coded from three official sources: the U.S. SAFECOM system (122), the
[...] Read more.
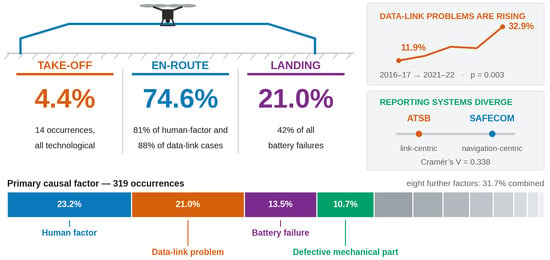
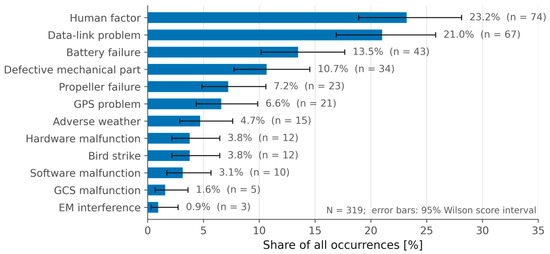
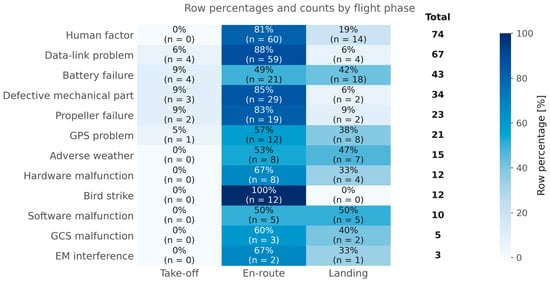
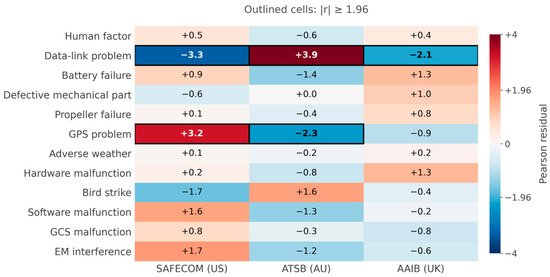
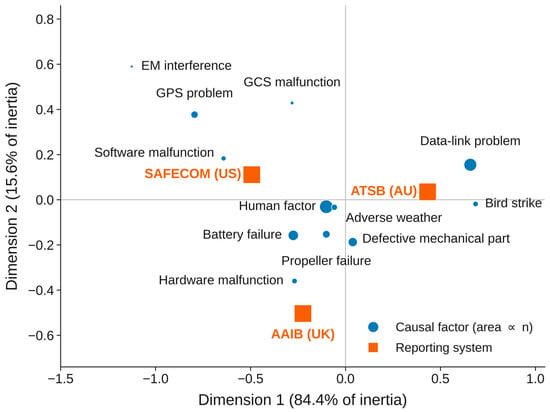
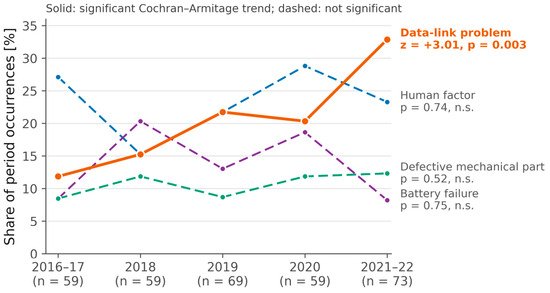
Multi-rotor unmanned aircraft systems (UAS) are now pervasive, yet quantitative evidence on how and why they fail remains fragmented across heterogeneous national reporting systems. This study analyses 319 multi-rotor UAS occurrences (2016–2022) coded from three official sources: the U.S. SAFECOM system (122), the Australian Transport Safety Bureau database (159) and the U.K. Air Accidents Investigation Branch reports (38). Each occurrence was assigned a primary causal factor from a twelve-factor taxonomy and a flight phase (take-off, en route, landing). Analyses comprised distributional estimation with Wilson confidence intervals, chi-squared association tests with permutation p-values for sparse tables, Cochran–Armitage trend tests, and correspondence analysis. Human factors (23.2%, 95% CI 18.9–28.1) and data-link problems (21.0%, CI 16.9–25.8) dominated, and 74.6% of occurrences arose en route—a phase profile opposite to that of manned aviation. Cause and phase were significantly associated (permutation p < 0.001, Cramér’s V = 0.305): all take-off occurrences were technological, none human-related, and battery failures clustered in landing (42%). Causal profiles differed markedly between reporting systems (p < 0.0001, V = 0.338), cautioning against naive pooling, and data-link problems nearly tripled from 11.9% (2016–17) to 32.9% (2021–22). Findings inform operator training, link redundancy, battery management and reporting standardisation.
Full article
(This article belongs to the Section Computational Engineering)
►▼
Show Figures

Graphical abstract
Open AccessArticle
HERA-GM: Evaluating Conditional Execution Authority for Offline Reinforcement Learning in Tactical Driving
by
Mohammad Al Khaldy, Ameen Shaheen and Youcef Gheraibia
Computation 2026, 14(9), 213; https://doi.org/10.3390/computation14090213 - 10 Sep 2026
Abstract
HERA-GM separates an offline learned tactical proposal from the authority to execute it. A Dueling Double DQN trained with Conservative Q-Learning proposes one of five tactical actions. The runtime process then uses the action-value margin, semantic feature availability, annotation density, a Mahalanobis diagnostic,
[...] Read more.
HERA-GM separates an offline learned tactical proposal from the authority to execute it. A Dueling Double DQN trained with Conservative Q-Learning proposes one of five tactical actions. The runtime process then uses the action-value margin, semantic feature availability, annotation density, a Mahalanobis diagnostic, and fixed hard-rule conditions to assign ACCEPT, DEFER, or RECOVER. The study separately examined proposer agreement, authority changes, closed-loop outcomes, and held-out-family discrimination. The original frozen evaluation used 113 nuPlan Mini scenarios from 39 logs and 1970 closed-loop runs. An additional exploratory behavior-cloning block added 339 runs. Behavior cloning had slightly higher offline macro-F1 than CQL, whereas DDQN without CQL had much lower agreement under the tested configurations. The main comparison between M1 and the simpler B3 gate showed no supported primary safety difference, indicating limited added endpoint effect from Mahalanobis and hard-rule evidence in this cohort. M1 also showed lower safety-failure and drivable-area violation rates than behavior cloning, but with lower conditional progress; the primary result did not remain below 0.05 after pooled Holm adjustment across the five clean comparisons. The Mahalanobis score did not distinguish held-out semantic families reliably. The findings describe the operating trade-offs and limits of conditional execution authority rather than a safety guarantee.
Full article
(This article belongs to the Special Issue Computational Intelligence for Trustworthy Decision-Making in Autonomous Systems)
►▼
Show Figures

Graphical abstract
Open AccessArticle
Float32-Induced Distortion in Activation Patching: Precision Floors and Displacement-Dependent Endpoint-Curvature Error
by
Yash Baligar
Computation 2026, 14(9), 212; https://doi.org/10.3390/computation14090212 - 9 Sep 2026
Abstract
Interaction-level activation patching is used to infer nonlinear cooperation in neural networks, but its numerical validity has not been systematically audited. In two pretrained checkpoints—GPT-2-medium and Pythia-410M, audited on one CUDA backend with a single templated cloze task family—we identified two independent failure
[...] Read more.
Interaction-level activation patching is used to infer nonlinear cooperation in neural networks, but its numerical validity has not been systematically audited. In two pretrained checkpoints—GPT-2-medium and Pythia-410M, audited on one CUDA backend with a single templated cloze task family—we identified two independent failure modes. First, exact finite pair interactions subtract four forward evaluations while the target scales as , creating a precision floor. In matched float32/float64 experiments, at a descriptive floor, 13.0% and 51.2% of full-displacement interactions fell below the threshold—across reasonable – cutoffs, these fractions ranged from 8.6 to 33.0% and from 39.5 to 82.1%, respectively—with sign disagreements of 2.9% and 13.2%; deterministic repetitions showed zero spread and therefore failed to expose the error. Second, even in float64, endpoint cross-Hessian estimates diverged from finite interactions as displacement increased, reaching 41–68% error at the full-replacement scale commonly used in patching; this displacement relationship is fitted on only these two checkpoints, and the Pythia-410M fit is visibly less stable. The corrupted prompts contain neither candidate answer, and the fixture’s behavioral contrast was not serialized at measurement time. A post hoc audit of the exact deposited fixture now confirms the intended contrast (the answer beats the distractor on all clean prompts in both models; the clean-minus-corrupt contrast is positive on and prompts). Thus, the quoted constants are properties of this behaviorally supported fixture and backend; we expect the audit procedure, not the constants, to transfer. We introduce an inexpensive scaling audit that detects cancellation floors and hidden mixed-precision bottlenecks; it exposed a hardcoded float32 softmax path inside nominal-float64 GPT-NeoX inference. A motivating negative result—that local logical gate topology does not predict attribution-patching error—was obtained under an author-held internal specification that is not independently timestamped and only in ten small synthetic transformers; it is untested at pretrained scale. These results show that reproducibility alone does not establish measurement validity and that precision error and endpoint approximation error must be audited separately. The proposed checks provide a practical validation standard for interaction-level mechanistic interpretability claims.
Full article
(This article belongs to the Section Computational Intelligence)
►▼
Show Figures

Graphical abstract
Open AccessArticle
Generalization of Defense Effects Learned from a Single Adversarial Attack
by
Dongxian Niu and Lin Shi
Computation 2026, 14(9), 211; https://doi.org/10.3390/computation14090211 - 9 Sep 2026
Abstract
Adversarial attacks misled deep neural networks by injecting perturbations into input images. Training networks with adversarial examples defended against adversarial attacks. However, training with specific adversarial examples only defended against the corresponding attacks. To generalize the defense effect from one specific attack to
[...] Read more.
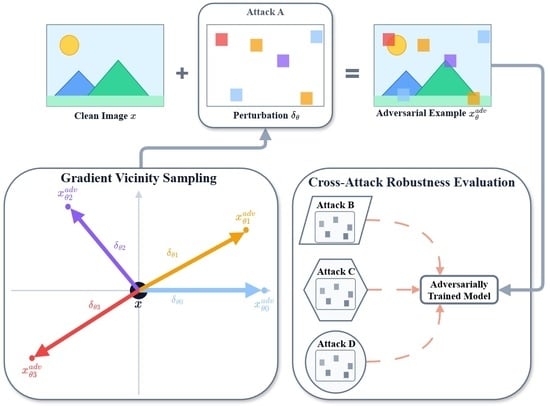
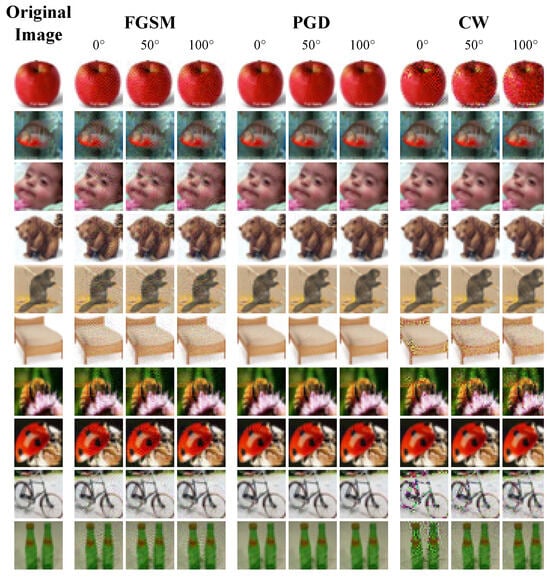
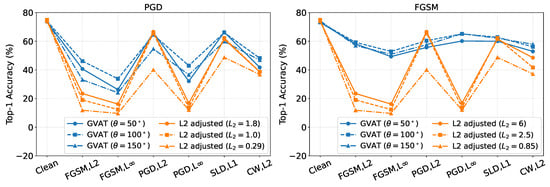
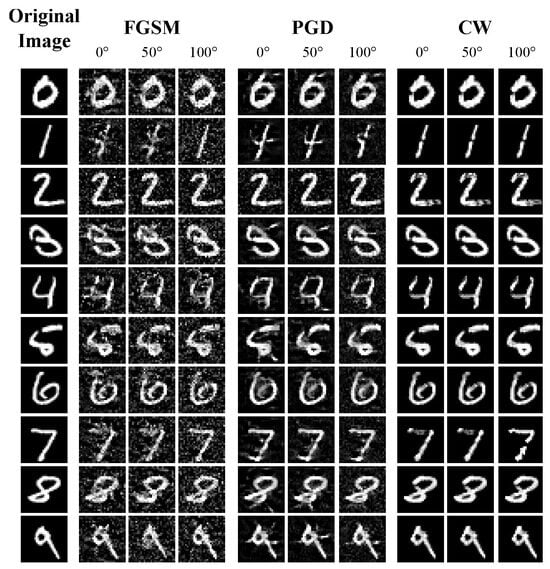
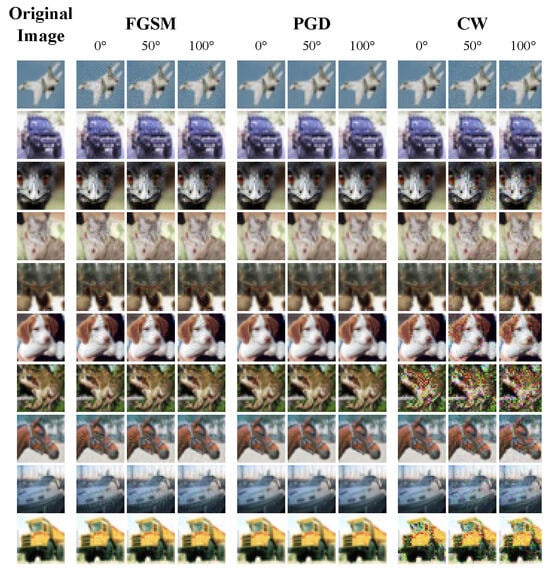
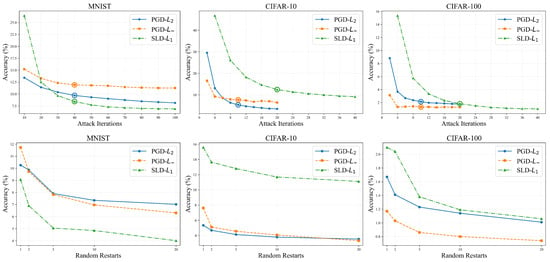
Adversarial attacks misled deep neural networks by injecting perturbations into input images. Training networks with adversarial examples defended against adversarial attacks. However, training with specific adversarial examples only defended against the corresponding attacks. To generalize the defense effect from one specific attack to other attacks, we proposed a method called Gradient Vicinity Adversarial Training (GVAT), which generated adversarial examples along directions sampled in the vicinity of the gradient. The defense effects of GVAT were evaluated using three attack methods: fast gradient sign method (FGSM), projected gradient descent (PGD), and Carlini–Wagner (CW) under the -norm constraint. A three-layer convolutional network was trained on the MNIST dataset, and two WideResNet-28-10 networks were trained on the CIFAR-10 and CIFAR-100 datasets respectively. Under the transfer-based black-box setting, the results showed that GVAT not only defended against the corresponding attacks that generated adversarial examples but also defended against other attacks. In other words, the defense effect of GVAT was generalized to other attacks under the transfer-based black-box setting.
Full article
(This article belongs to the Special Issue Computational Methods for Multi-View Representation Learning)
►▼
Show Figures

Graphical abstract
Open AccessArticle
GuidelineGuard: An Agentic Retrieval-Augmented Generation Framework with Sentence-Level Citation Auditing for Guideline-Grounded Question Answering
by
Farida Far Poor
Computation 2026, 14(9), 210; https://doi.org/10.3390/computation14090210 - 9 Sep 2026
Abstract
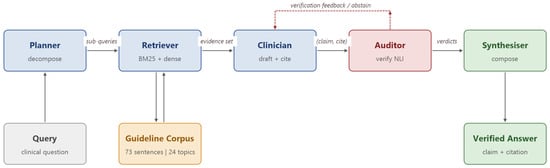
Background: Large language models (LLMs) can produce clinically plausible recommendations that are not adequately supported by authoritative evidence. Objectives: We introduce GuidelineGuard, a modular multi-agent retrieval-augmented generation pipeline in which a separate Auditor verifies claim–sentence support before a recommendation is
[...] Read more.
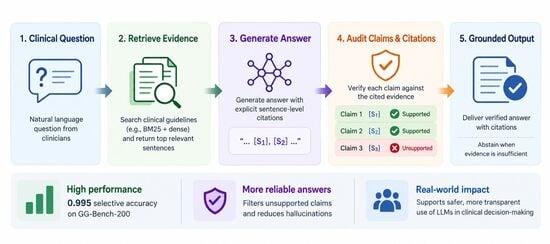
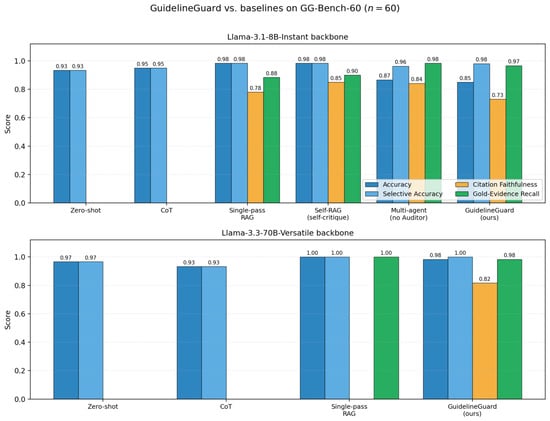
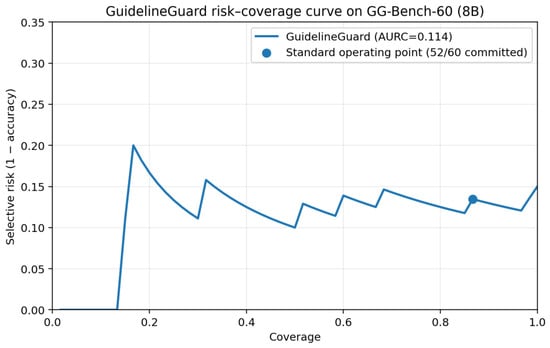
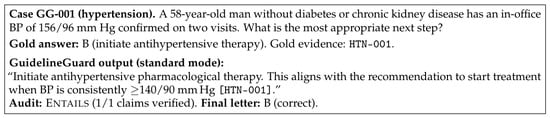
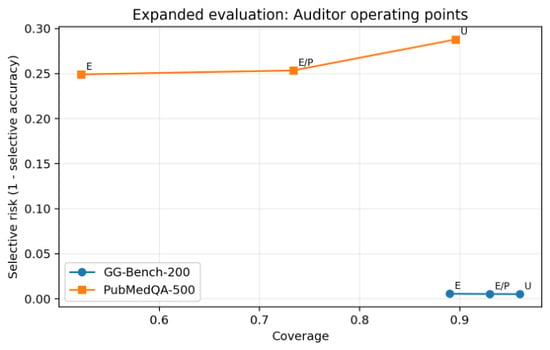
Background: Large language models (LLMs) can produce clinically plausible recommendations that are not adequately supported by authoritative evidence. Objectives: We introduce GuidelineGuard, a modular multi-agent retrieval-augmented generation pipeline in which a separate Auditor verifies claim–sentence support before a recommendation is surfaced. Methods: The original evaluation used a 73-sentence guideline corpus and GG-Bench-60, with replication across three open-weight backbones. In response to reviewer concerns about benchmark size and selective evaluation, we added a source-traceable GG-Bench-200 stress test and the complete 500-case held-out PQA-L test split of PubMedQA. The revision experiments compare single-pass RAG, a paired multi-agent no-Auditor ablation, and GuidelineGuard; the paired runner is designed to share the Planner–Retriever–Clinician draft so that the Auditor is the only intervention. Checkpoint verification confirmed an identical observable pre-audit state for all 200 GG-Bench cases and 496/500 PubMedQA cases; four PubMedQA cases were regenerated after quota-interrupted resumption and were correct commitments in both arms. Because the originally used hosted Llama endpoints became unavailable after the initial experiments, the expanded runs use openai/gpt-oss-20b for generation and openai/gpt-oss-120b for the Auditor. Results: On GG-Bench-200, single-pass RAG achieved 0.970 operational accuracy, while the no-Auditor and GuidelineGuard arms achieved 0.955 and 0.925, respectively. GuidelineGuard committed on 186/200 cases (coverage 0.930) and was correct on 185/186 commitments (selective accuracy 0.995); all 186 commitments cited at least one gold evidence identifier. Relative to the paired no-Auditor arm, the gate rejected six otherwise-correct commitments and no incorrect commitment. On PubMedQA-500, single-pass RAG achieved 0.644 operational accuracy at 0.950 coverage, the no-Auditor arm 0.638 at 0.896 coverage, and GuidelineGuard 0.550 at 0.736 coverage. Selective accuracy increased across those operating points from 0.678 to 0.712 to 0.747. Within the 496 PubMedQA cases with verified-identical observable pre-audit state, the gate rejected 36 incorrect and 45 correct pre-audit commitments, demonstrating both error enrichment and a substantial false-rejection cost. Conclusions: The expanded results support GuidelineGuard as a selective claim–evidence verification mechanism, not as a universally more accurate generator. Its value is the explicit, auditable coverage–risk trade-off; the appropriate verification threshold is task- and cost-dependent and requires prospective clinical validation.
Full article
(This article belongs to the Special Issue Applied Large Language Models for Science, Engineering, and Mathematics: Reasoning, Reliability and Efficient Systems)
►▼
Show Figures

Graphical abstract
Open AccessArticle
Word Counting Is Not Enough: A Syntax-Driven Computational Method for Analyzing Participation
by
María P. Raveau, Julián I. Goñi, Pía Amigo and Claudio Fuentes-Bravo
Computation 2026, 14(9), 209; https://doi.org/10.3390/computation14090209 - 9 Sep 2026
Abstract
Traditional methods of citizen deliberation, such as mini-publics, have been criticized for their limited scope. However, the implementation of massive deliberative processes creates new socio-technical challenges, particularly at the systematization stage. In general, the task of processing citizen participation is typically met with
[...] Read more.
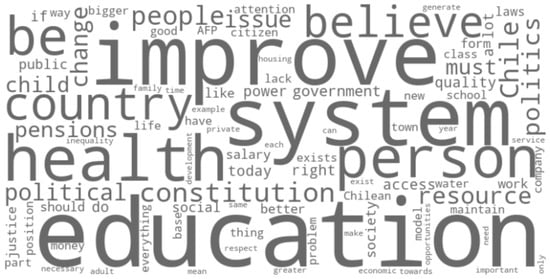
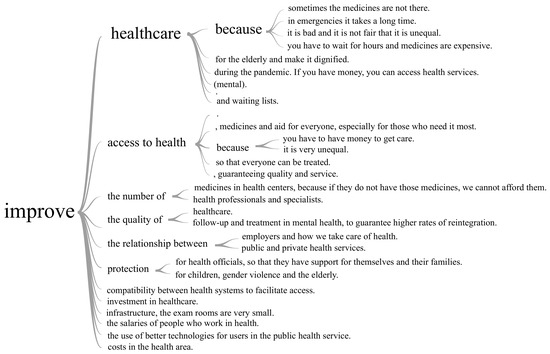
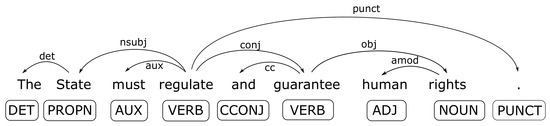
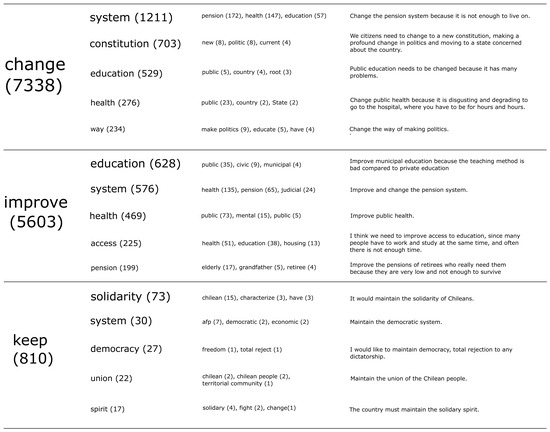
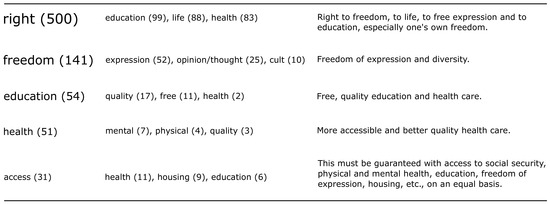
Traditional methods of citizen deliberation, such as mini-publics, have been criticized for their limited scope. However, the implementation of massive deliberative processes creates new socio-technical challenges, particularly at the systematization stage. In general, the task of processing citizen participation is typically met with the general tools of textual analysis and Natural Language Processing (NLP). However, processing participation is not just a technical problem, but fundamentally a problem of normative design whose solution must be coherent with the philosophical, ethical, and institutional decisions that the participatory process embodies. In this article, we show how, using basic syntactic rules, we can produce simple and highly explainable reconstructions of public opinions. This methodology was tested on datasets from Chilean participatory processes, specifically dialogs from We have to talk about Chile and the 2023 Constituent Process. We show how our strategy enables further information extraction by identifying different syntactic components, providing deeper insights into the answers, while aligning with the goals of citizen participation. Overall, this study presents a compelling alternative for interpreting large volumes of citizen input, particularly in ways that preserve context and advance a more coherent analytical framework aligned with the normative ideals of deliberative democracy.
Full article
(This article belongs to the Special Issue Computational Social Science and Complex Systems—2nd Edition)
►▼
Show Figures

Figure 1
Open AccessArticle
A Physics-Informed Neural Network Framework for Lossy Telegrapher Equations with a Formulated Multi-Physics Environmental Extension
by
Mohammad (Behdad) Jamshidi
Computation 2026, 14(9), 208; https://doi.org/10.3390/computation14090208 - 8 Sep 2026
Abstract
This paper develops a physics-informed neural network (PINN) framework for the lossy telegrapher equations and presents a coupled IEEE 738 thermal balance formulation intended as a structural blueprint for environmentally aware transmission-line digital twins. The baseline electromagnetic PINN maps
[...] Read more.
This paper develops a physics-informed neural network (PINN) framework for the lossy telegrapher equations and presents a coupled IEEE 738 thermal balance formulation intended as a structural blueprint for environmentally aware transmission-line digital twins. The baseline electromagnetic PINN maps and is empirically validated against a finite-difference time-domain (FDTD) reference solver. An augmented parametric framework is mathematically derived, wherein the ambient vector modulates a temperature-dependent resistance and couples to the telegrapher residuals via a non-linear thermal balance residual . Two further constraints, a sag-tension consistency residual and a dynamic line rating (DLR) one-sided penalty , are formulated for completeness but are explicitly designated as architectural extension hooks running at zero weight ( ) within the reported microscale numerical benchmarks. Consequently, the empirical validation presented herein strictly concerns the baseline electromagnetic telegrapher PINN. The numerical results demonstrate robust field convergence against FDTD reference data, highly structured error accumulation along physical characteristic curves, and reliable recovery of strongly observable parameters from sparse, noisy terminal measurements. Conversely, the recovery of loss parameters exhibits a severe structural weak identifiability that precisely matches the analytical predictions of a comprehensive Fisher Information Matrix analysis. The core contributions of this work are primarily methodological: (i) a dimensionally consistent, corrected residual formulation for the lossy telegrapher equations; (ii) an explicit positioning of the proposed multi-physics framework within the parametric PINN literature; (iii) a Fisher information identifiability diagnostic illustrating the near-degeneracy of baseline parameter estimation; and (iv) a clean algorithmic separation of forward training, inverse parameter identification, and prospective online updates.
Full article
(This article belongs to the Special Issue Computational Methods for Advanced Digital Twins in Biological and Engineered Systems)
►▼
Show Figures

Figure 1
Open AccessArticle
A Simulation-Based Quantum-Synchronized Ephemeral Encryption Framework for QKD-Secured IoT Networks with Transformer-Based Cyber-Quantum Attack Detection
by
Mohammad Sameer Aloun, Ala Mughaid, Bashar S. Khassawneh and Mahmoud AlJamal
Computation 2026, 14(9), 207; https://doi.org/10.3390/computation14090207 - 7 Sep 2026
Abstract
This paper presents a simulation-based cyber-quantum Internet of Things (IoT) security framework for modeling, securing, and detecting attacks in QKD-secured IoT communication environments. The proposed framework integrates heterogeneous IoT traffic generation, gateway-assisted routing, edge processing, QKD key-pool management, Quantum-Synchronized Ephemeral Encryption (Q-SEE), cross-layer
[...] Read more.
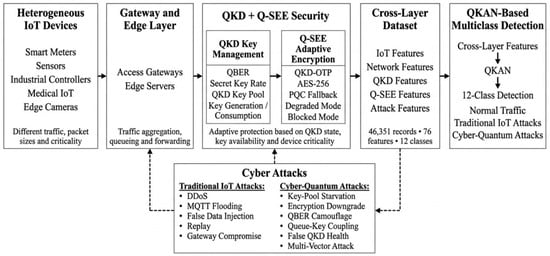
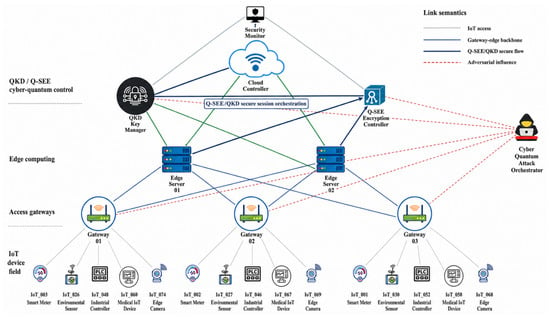
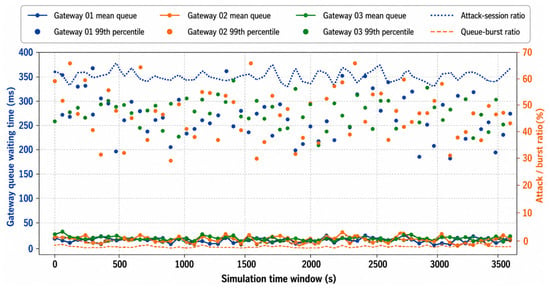
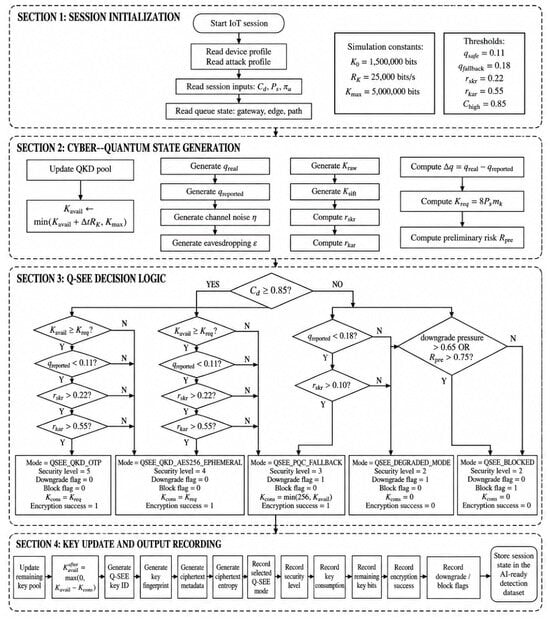
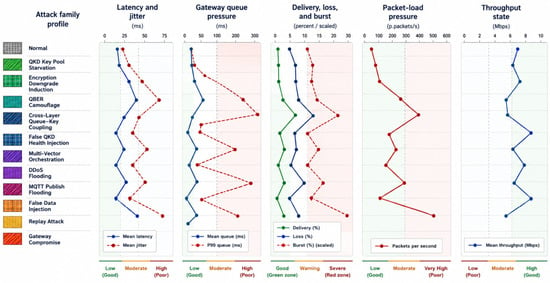
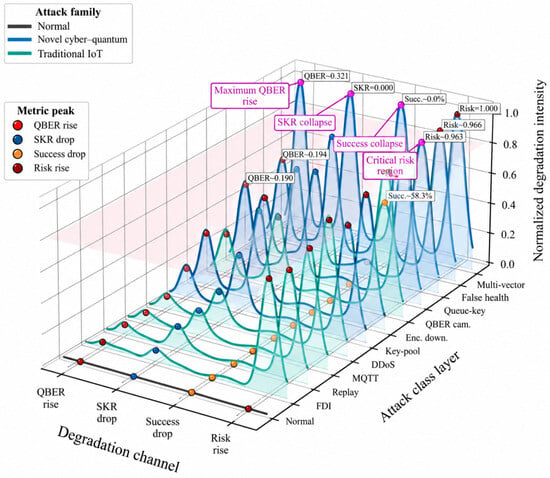
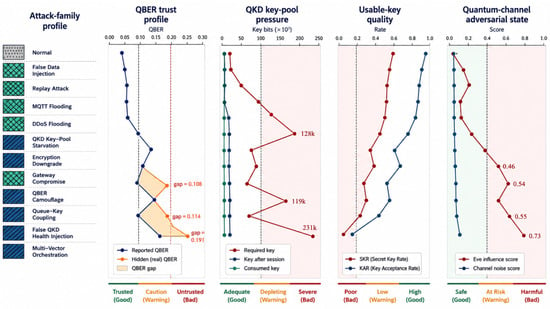
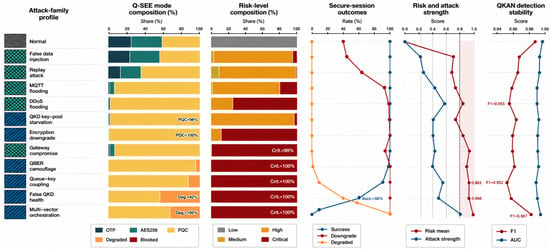
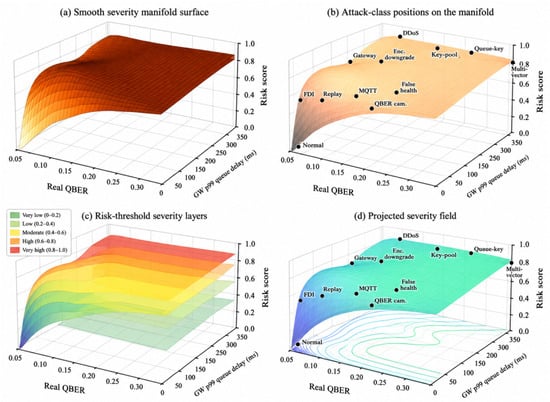
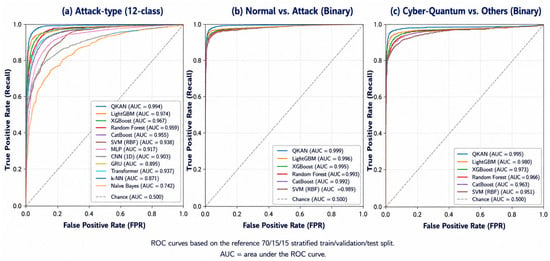
This paper presents a simulation-based cyber-quantum Internet of Things (IoT) security framework for modeling, securing, and detecting attacks in QKD-secured IoT communication environments. The proposed framework integrates heterogeneous IoT traffic generation, gateway-assisted routing, edge processing, QKD key-pool management, Quantum-Synchronized Ephemeral Encryption (Q-SEE), cross-layer adversarial attack injection, and AI-based multiclass detection. Unlike conventional IoT intrusion datasets that mainly capture packet- or flow-level abnormalities, the generated dataset represents the joint behavior of IoT sessions, network delay, queue pressure, QKD state, key consumption, encryption-mode transitions, ciphertext metadata, and cyber-quantum risk. A Python/SimPy/NetworkX simulation was developed using 80 IoT devices, 3 gateways, 2 edge servers, 4 cyber-quantum control-plane nodes, and 1 adversarial orchestrator. The final simulation produced 46,351 records with 76 features covering normal traffic, five traditional IoT attacks, and six novel cyber-quantum attacks, including QKD key-pool starvation, QBER camouflage, false QKD-health injection, encryption downgrade induction, queue–key coupling, and multi-vector cyber-quantum orchestration. Q-SEE adaptively selects among QKD-OTP, QKD-synchronized AES-256 ephemeral mode, PQC fallback, degraded mode, and blocked mode according to QBER, secret key rate, key availability, device criticality, downgrade pressure, and risk. A leakage-aware Quantum-Aware Kolmogorov–Arnold Network (QKAN) was then trained using deployable cyber-quantum evidence. The final nonrisk QKAN achieved 98.79% test accuracy, 98.61% macro-F1, 98.85% weighted-F1, and 99.78% macro-AUC, demonstrating effective detection of traditional and cyber-quantum IoT attacks.
Full article
(This article belongs to the Section Computational Intelligence)
►▼
Show Figures

Figure 1
Open AccessArticle
YOLO-Based Object Localization and Classification in UAV Images Compressed by JPEG
by
Rostyslav Tsekhmystro, Vladimir Lukin and Dmytro Krytskyi
Computation 2026, 14(9), 206; https://doi.org/10.3390/computation14090206 - 7 Sep 2026
Abstract
Methods for object localization and classification in images acquired from unmanned aerial vehicles (UAVs) quickly develop and find new applications. Pre-trained convolutional neural networks (CNNs) play the key role in solving these tasks. However, there are many factors that degrade the quality of
[...] Read more.
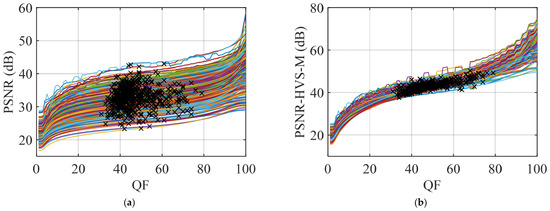
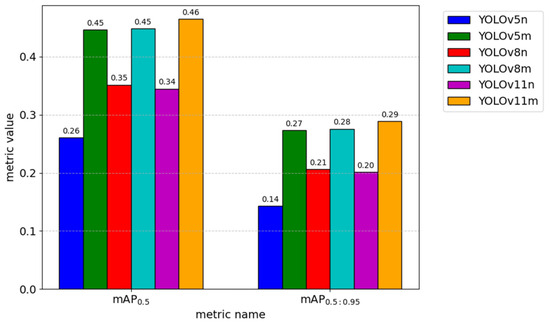
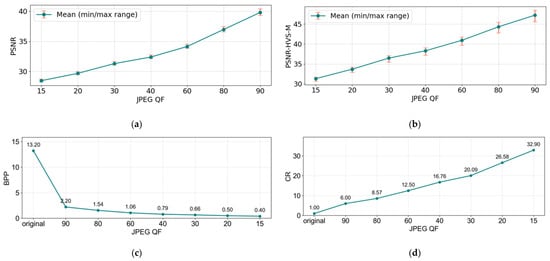
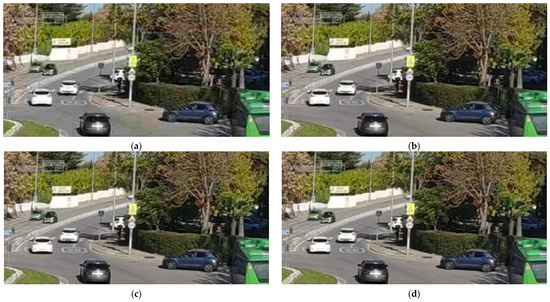
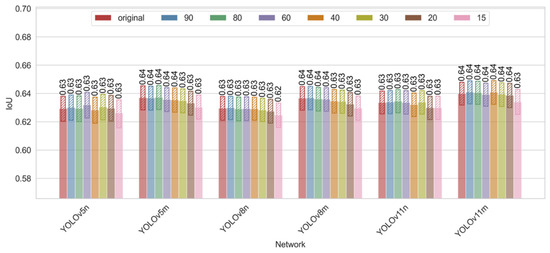
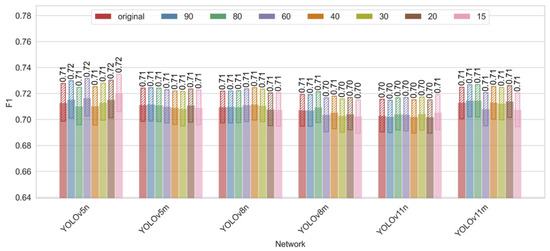
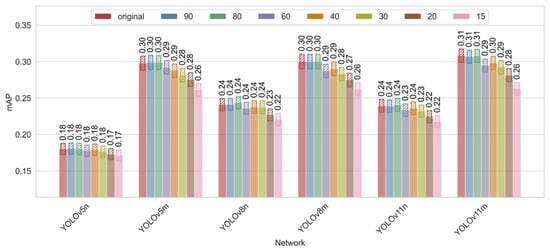
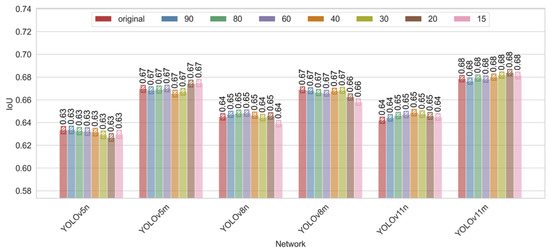
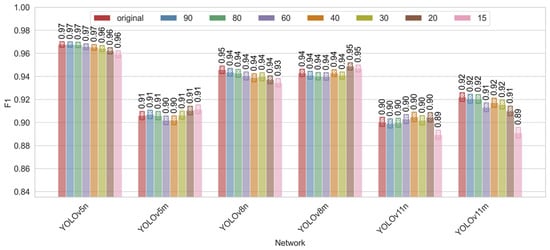
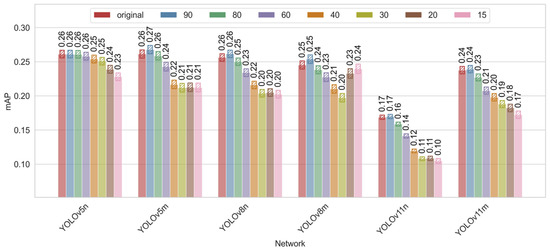
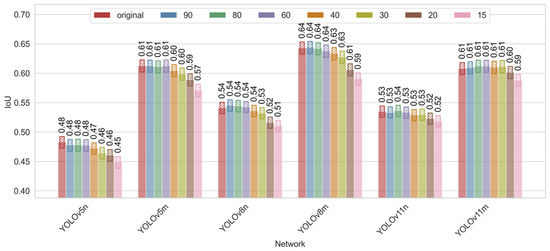
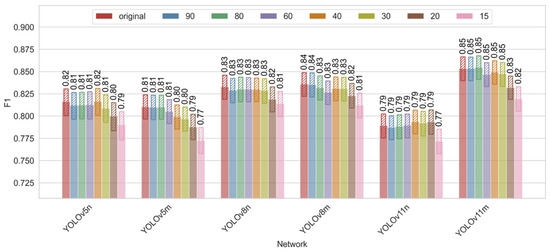
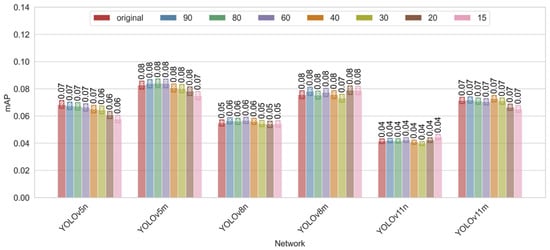
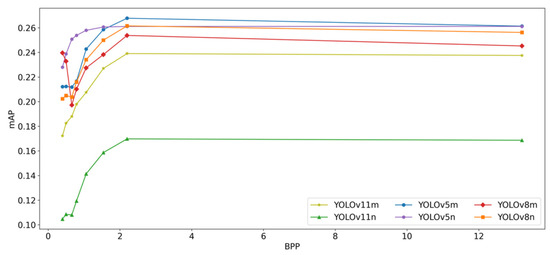
Methods for object localization and classification in images acquired from unmanned aerial vehicles (UAVs) quickly develop and find new applications. Pre-trained convolutional neural networks (CNNs) play the key role in solving these tasks. However, there are many factors that degrade the quality of acquired images and make the performance of methods intended for object detection and classification worse. One such factor is lossy compression of acquired images or video data widely used to pass them from on-board sensors and devices of preliminary data processing to on-land centers that perform further data processing for retrieval of valuable information. Both CNNs applied for localization and classification, and lossy compression techniques used to reduce the transferred data size have an impact on final results. To study this impact, we analyze the performance of several modifications of YOLO (You Only Look Once) CNNs applied to color images compressed by JPEG, which continues to be one of the basic compression tools. The quality factor is varied within wide limits to detect the situation when distortions due to lossy compression start to become too large and have a considerable negative effect on the localization and classification of objects of different types and sizes. Analysis is carried out using several traditional criteria, including Intersection over Union, F1, and mAP metrics, as well as some others. Dependence of localization and classification characteristics on the object size is performed. The datasets VisDrone and TAI are employed in training and verification.
Full article
(This article belongs to the Special Issue Integrated Computer Technologies in Mechanical Engineering—Synergetic Engineering V)
►▼
Show Figures

Figure 1
Open AccessArticle
Enhancement of Performances of the Simplex Finite Elements by Applying the Strain-Smoothed Element Method
by
Marija M. Rafailović, Miroslav M. Živković, Vladimir P. Milovanović, Jelena M. Živković, Slobodan R. Savić and Saša T. Milojević
Computation 2026, 14(9), 205; https://doi.org/10.3390/computation14090205 - 5 Sep 2026
Abstract
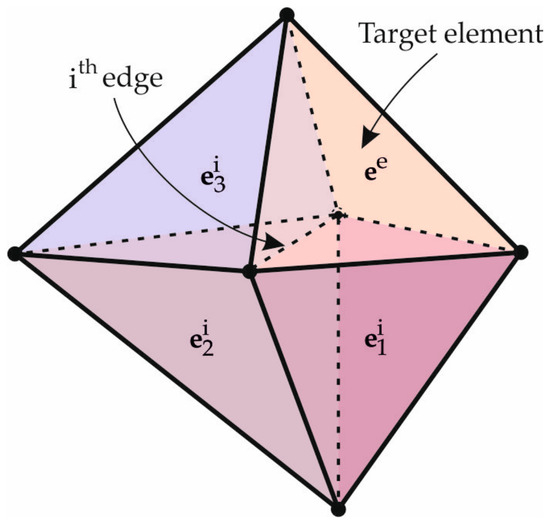
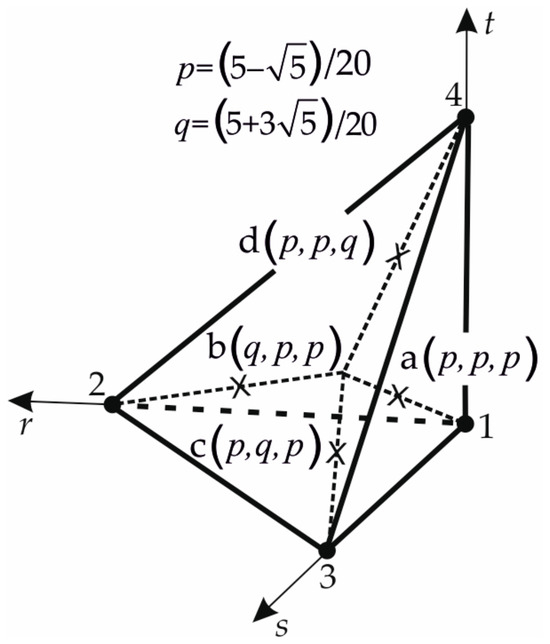
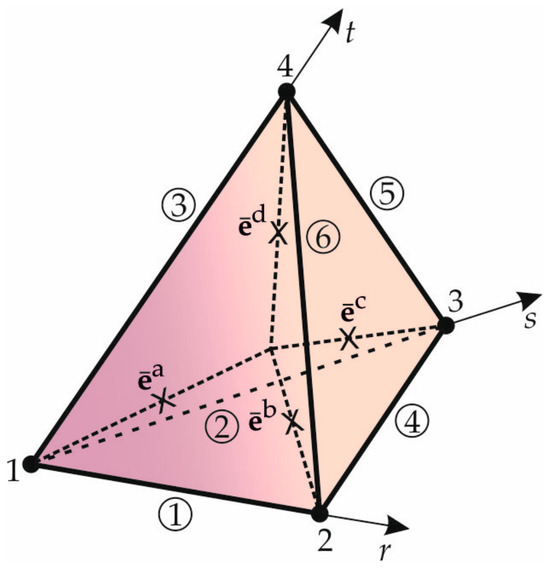
This paper presents the strain-smoothed element (SSE) method applied to the 4-node tetrahedral finite element. The unique characteristic of the SSE method represents constructing a smoothed strain field for the elements, rather than for the smoothing domains, whereby the constant strains of all
[...] Read more.
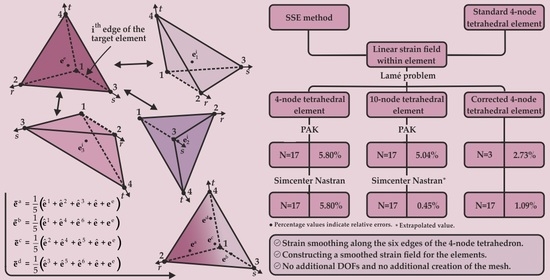
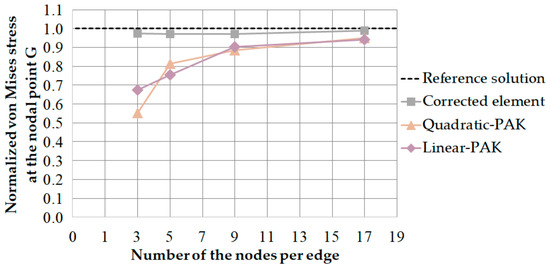
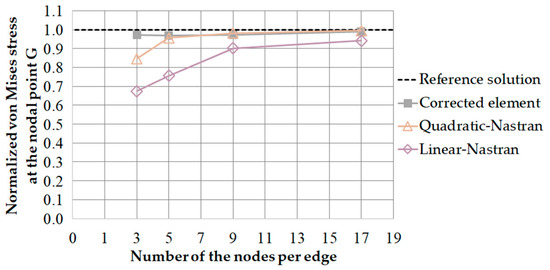
This paper presents the strain-smoothed element (SSE) method applied to the 4-node tetrahedral finite element. The unique characteristic of the SSE method represents constructing a smoothed strain field for the elements, rather than for the smoothing domains, whereby the constant strains of all adjacent elements are fully utilized for the strain smoothing of the target element. Consequently, a linear strain field within the 4-node tetrahedral finite element is constructed through four Gauss integration points. The method does not require any additional creation of the mesh, and a standard isoparametric formulation of the 4-node tetrahedral finite element is used to formulate it. A numerical example was used to demonstrate the stress prediction improvement achieved as regards the corrected element, as taken from Chaemin Lee and Phill-Seung Lee’s publication of the method itself, compared with the linear and quadratic tetrahedral finite elements, which are implemented within the PAK and Simcenter Nastran software packages. The numerical results show that stresses predicted by the strain-smoothed 4-node tetrahedral finite element are comparable to that of a 10-node tetrahedral finite element that incorporates an extrapolation process for the determination of nodal stress values.
Full article
(This article belongs to the Section Computational Engineering)
►▼
Show Figures

Graphical abstract
Open AccessArticle
Learning Subgroup Relations Using Siamese Graph Neural Networks
by
Tal Weissblat
Computation 2026, 14(9), 204; https://doi.org/10.3390/computation14090204 - 2 Sep 2026
Abstract
Determining whether one finite group is isomorphic to a subgroup of another is a fundamental problem in computational group theory. In this work, we propose a Siamese Graph Neural Network (Siamese GNN) for subgroup prediction using Cayley graph representations of finite groups. Each
[...] Read more.
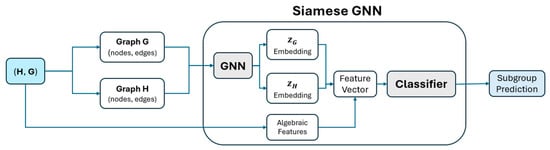
Determining whether one finite group is isomorphic to a subgroup of another is a fundamental problem in computational group theory. In this work, we propose a Siamese Graph Neural Network (Siamese GNN) for subgroup prediction using Cayley graph representations of finite groups. Each input group is represented by its undirected Cayley graph and encoded by one branch of a Siamese GNN to produce a graph embedding. The resulting graph embeddings are combined with algebraic features derived directly from the input groups to construct a joint feature vector, which is processed by a fully connected classifier to predict subgroup relations between finite groups. By integrating graph-based structural representations with algebraic features, the proposed framework provides a unified approach for learning subgroup relations from finite groups. Experimental results on an expanded and more diverse dataset of 308 finite-group pairs drawn from 11 group families demonstrate the effectiveness of the proposed architecture, achieving a test BA of 91.67% on an independent test set. Additional experiments evaluate generalization to unseen groups, robustness to different Cayley graph generating sets, the contribution of GNN message passing, performance relative to non-neural baselines, and comparison with exact computational methods. These results illustrate the potential of geometric deep learning for subgroup prediction.
Full article
(This article belongs to the Section Computational Intelligence)
►▼
Show Figures

Figure 1
Open AccessArticle
Discrete Riccati and Comparison Approaches to Oscillation of Second-Order Advanced Difference Equations with Multiple Deviating Arguments
by
K. Masaniammal, R. Ramesh, Chathura Wanigasekara, Vadivel Rajarathinam and R. Suresh
Computation 2026, 14(9), 203; https://doi.org/10.3390/computation14090203 - 2 Sep 2026
Abstract
In this work, we develop, from first principles, a discrete oscillation theory for second-order nonlinear advanced difference equations with several deviating arguments,
[...] Read more.
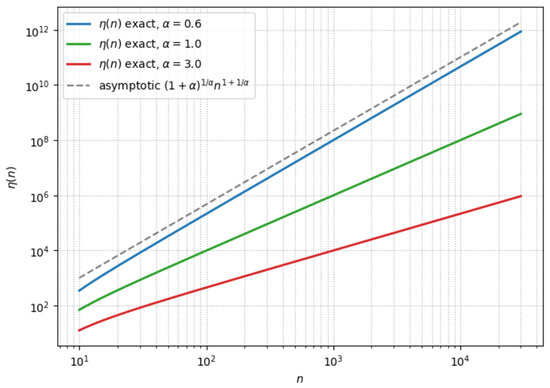
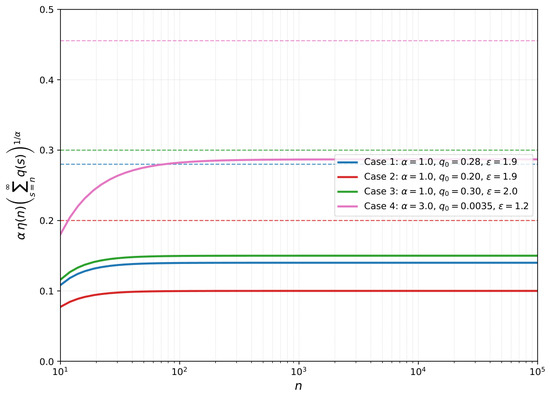
In this work, we develop, from first principles, a discrete oscillation theory for second-order nonlinear advanced difference equations with several deviating arguments, studied under the canonical condition This equation models discrete systems governed by anticipatory rather than delayed dynamics, since the second-order difference term depends on a future value rather than a past one. We prove an iterative monotonicity lemma, a classification lemma for eventually positive solutions, three oscillation results, a comparison theorem, and a Riccati-type theorem. Two features that are unique to the discrete setting, with no counterpart in the continuous theory, are highlighted. First, the partial sum typically lacks a closed form and must be approximated asymptotically. Second, the discrete Riccati step requires an additional power-rule inequality, which introduces a correction term absent from the continuous case. The theoretical thresholds obtained are illustrated by a fully worked example, verified both numerically and symbolically and supported by figures.
Full article
(This article belongs to the Special Issue Nonlinear System Modelling and Control—2nd Edition)
►▼
Show Figures

Figure 1
Open AccessArticle
Fractional Evolution on Anatomy-Derived Aortic Branch Graphs: Multiresolution Geometry, Observation Leakage, and Controlled Off-Grid Joint Identifiability
by
Jiayin Li
Computation 2026, 14(9), 202; https://doi.org/10.3390/computation14090202 - 1 Sep 2026
Abstract
A fractional graph-evolution model is formulated on a surface-derived thoracic-aortic branch tree and evaluated through multiresolution geometry and controlled joint-parameter experiments. A checksum-tracked source audit separates three model-specific MRI collections from a shared nominal wall surface and confirms that no validated MRI–STL transformation
[...] Read more.
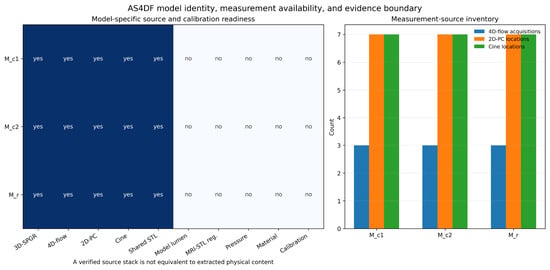
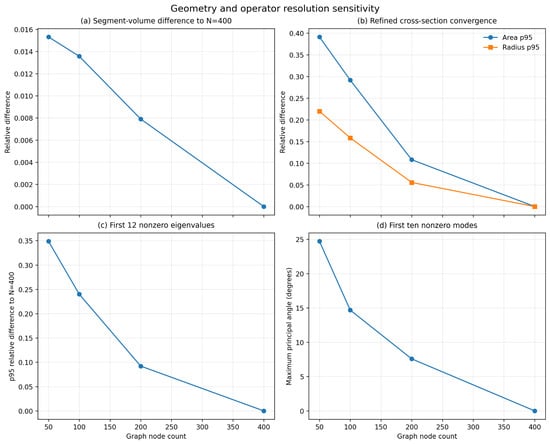
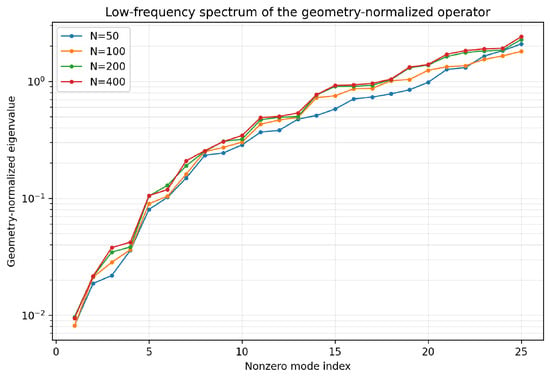
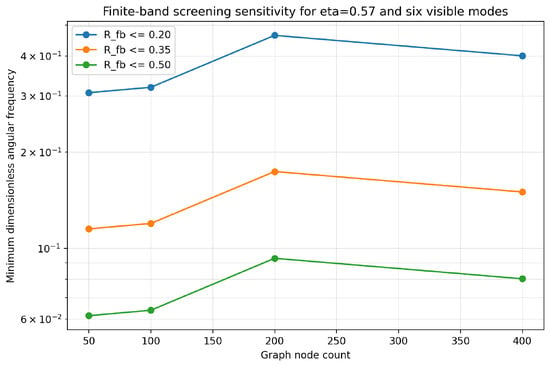
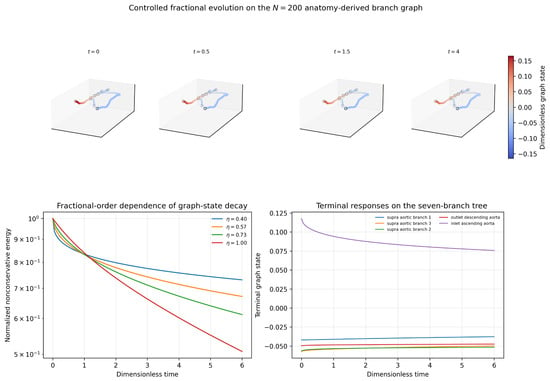
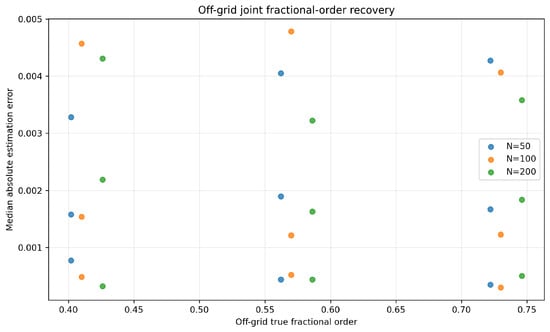
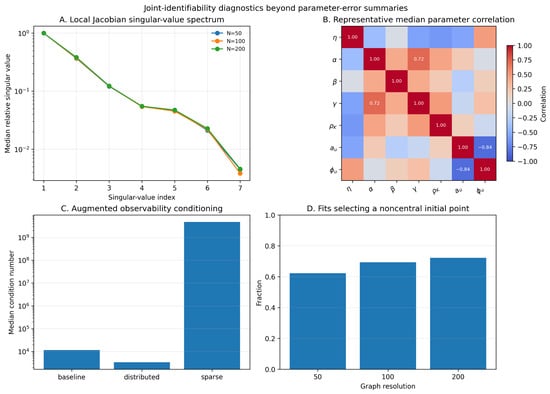
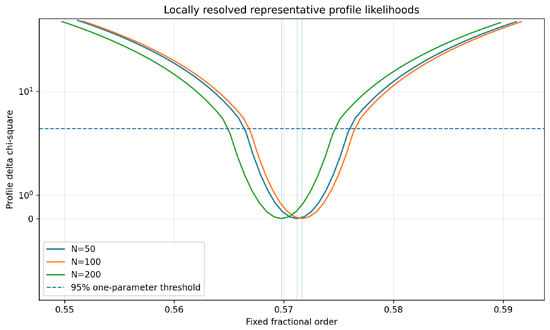
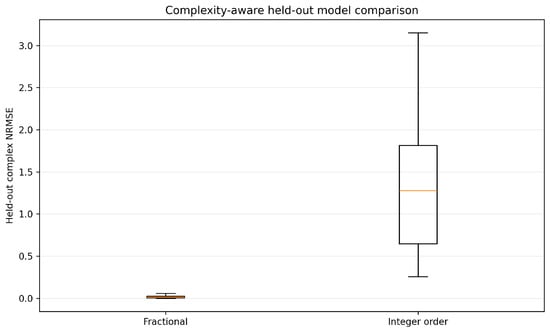
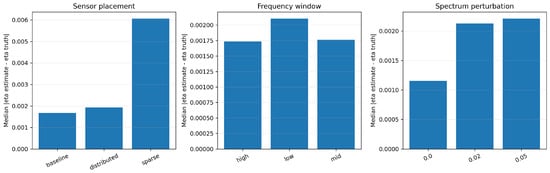
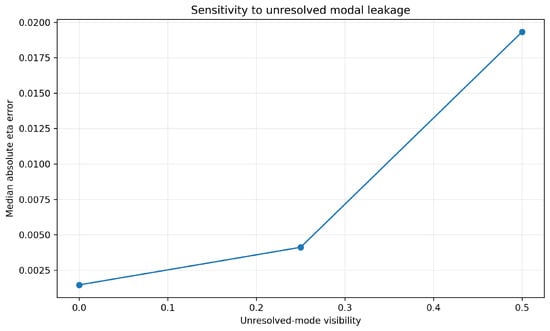
A fractional graph-evolution model is formulated on a surface-derived thoracic-aortic branch tree and evaluated through multiresolution geometry and controlled joint-parameter experiments. A checksum-tracked source audit separates three model-specific MRI collections from a shared nominal wall surface and confirms that no validated MRI–STL transformation is available. The surface pipeline yields five terminal openings, three junctions, seven semantic branches, refined cross-sections, and an unapproved same-source candidate. Consequently, the instantiated operator is dimensionless and geometry normalized, rather than a calibrated pressure–flow operator. Graphs with 50, 100, 200, and 400 nodes preserve topology; relative to the internal 400-node discretization, the 200-node graph has a 9.20% 95th-percentile discrepancy in the first 12 positive eigenvalues and a 7.58° maximum principal angle for the first 10 modal subspaces. The analysis establishes a Caputo-consistent control-volume reduction, finite-horizon well-posedness for bounded forcing, non-normal augmented dynamics, observation leakage, finite-band phase conditions, and residual power-law stability. In 810 off-grid synthetic experiments, seven parameters are estimated jointly with repeated noise, multistart optimization, profile likelihood, and held-out testing. The median fractional-order error is 0.001304 and the median held-out complex NRMSE is 0.01086. The results support controlled synthetic practical identifiability on a shared nominal anatomy, not measured hemodynamic calibration or physiological-memory identification.
Full article
(This article belongs to the Section Computational Biology)
►▼
Show Figures

Figure 1
Open AccessArticle
A Schur-Consistent GPU CPRW–AMG Preconditioner for Well-Coupled Fully Implicit Multiphase Flow Simulation
by
Xiangling Meng, Yisen Qin and Huayu Li
Computation 2026, 14(9), 201; https://doi.org/10.3390/computation14090201 - 1 Sep 2026
Abstract
Fully implicit simulation of multiphase flow in porous media requires repeated solution of large, sparse, nonsymmetric Jacobian systems, where linear solvers and preconditioners often dominate the computational cost. In field-scale models with strong well controls and well–reservoir coupling, bottom-hole pressure (BHP) constraints may
[...] Read more.
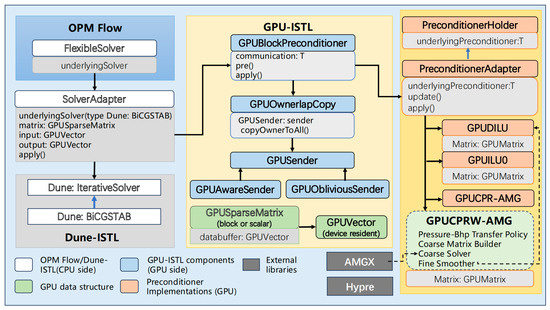
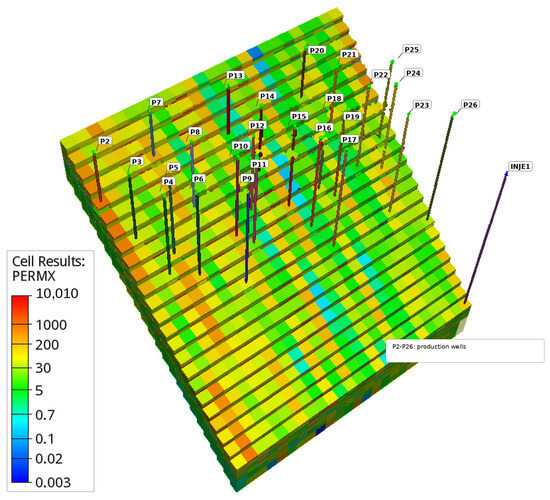
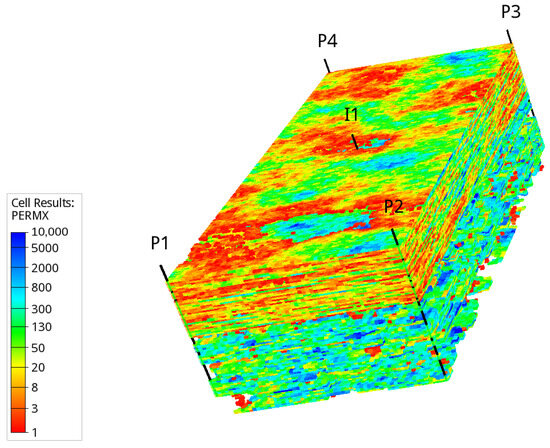
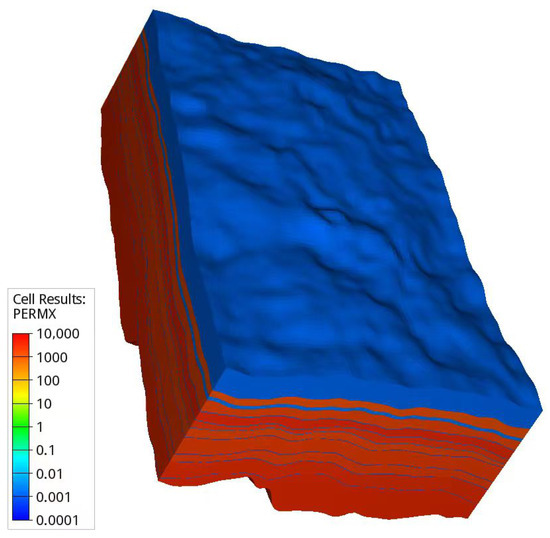
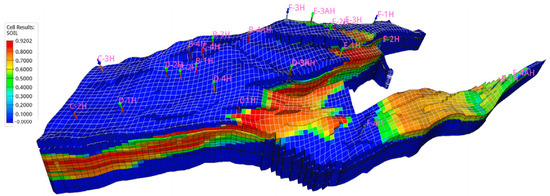
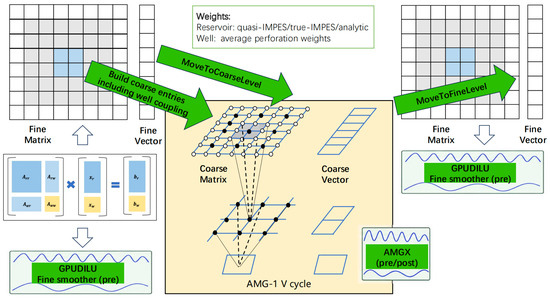
Fully implicit simulation of multiphase flow in porous media requires repeated solution of large, sparse, nonsymmetric Jacobian systems, where linear solvers and preconditioners often dominate the computational cost. In field-scale models with strong well controls and well–reservoir coupling, bottom-hole pressure (BHP) constraints may introduce slowly converging pressure-related error modes that are not fully represented by pressure-only constrained pressure residual (CPR) preconditioning. This paper develops a Schur-consistent graphics processing unit (GPU) implementation of constrained pressure residual with wells and algebraic multigrid (CPRW-AMG) for the Open Porous Media (OPM) Flow simulator. The method augments the pressure coarse space with one auxiliary BHP unknown per active well while preserving a reservoir-only fine-level Krylov system. The pressure–BHP coarse operator is constructed from the same assembled effective reservoir Jacobian used by the Krylov matrix–vector product and the GPU diagonal incomplete lower–upper (DILU) smoother, avoiding inconsistent treatment of well contributions between fine and coarse levels. A GPU-resident sparse update strategy refreshes well-related coarse entries, and the NVIDIA AMGX library is used for the scalar coarse solve. Benchmarks on SPE9, SPE10, Sleipner, and Norne cover small well-coupled, highly heterogeneous carbon dioxide storage and field-realistic reservoir models. Compared with CPU CPRW-AMG, the GPU implementation reduces total runtime by factors of 1.69–8.78 and achieves linear-solve speedups of up to 17.96×. Compared with GPU CPR-AMG, the performance benefit is case-dependent, indicating that CPRW-AMG is most effective when the reduction in well-induced slow error modes compensates for the additional coarse-level cost.
Full article
(This article belongs to the Special Issue Advances in Computational Methods for Fluid Flow—2nd Edition)
►▼
Show Figures

Figure 1
Open AccessArticle
Resolvent-Free Inclusion Problems with Applications
by
Mujahid Abbas and Muhammad Waseem Asghar
Computation 2026, 14(9), 200; https://doi.org/10.3390/computation14090200 - 1 Sep 2026
Abstract
In this paper, we propose a resolvent-free and projection-free iterative algorithm to solve monotone inclusion problems. The proposed method employs a double inertial extrapolation strategy, in which two distinct inertial steps are used to construct two extrapolated points, together with a new self-adaptive
[...] Read more.
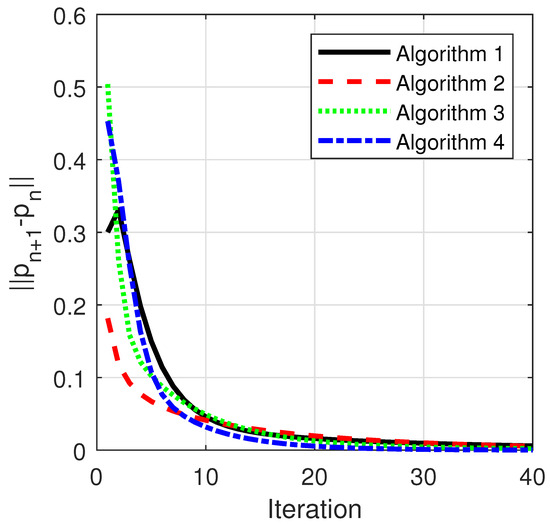
In this paper, we propose a resolvent-free and projection-free iterative algorithm to solve monotone inclusion problems. The proposed method employs a double inertial extrapolation strategy, in which two distinct inertial steps are used to construct two extrapolated points, together with a new self-adaptive step-size for selecting the inertial parameter in the proposed algorithm. This combination provides an effective strategy to incorporate information from two extrapolated directions without the metric projections and resolvent of an operator. Under suitable assumptions, we establish the strong convergence of the proposed sequence to a solution of the monotone inclusion problem. The obtained convergence result is further applied to minimax and critical point problems. Moreover, numerical experiments in finite and infinite dimensional spaces are presented to compare the proposed method with some existing resolvent-free and inertial schemes. The numerical results demonstrate that the proposed method achieves faster convergence in terms of the number of iterations and provides improved reconstruction performance, with higher SNR and lower MSE for the considered image restoration problems. Further, applications to image reconstruction and compressive sensing provide the practical effectiveness of the proposed approach.
Full article
(This article belongs to the Topic Iterative Methods: Theory, Dynamics, Algorithms, and Fractal Structures)
►▼
Show Figures

Figure 1
Highly Accessed Articles
Latest Books
E-Mail Alert
News
16 September 2026
Meet Us at the 24th Annual Meeting of the China Society for Industrial and Applied Mathematics (CSIAM 2026), 8–11 October 2026, Lanzhou, China
Topics
Topic in
Sustainability, Remote Sensing, Forests, Applied Sciences, Computation
Artificial Intelligence, Remote Sensing and Digital Twin Driving Innovation in Sustainable Natural Resources and Ecology
Topic Editors: Huaiqing Zhang, Ting YunDeadline: 31 January 2027
Topic in
Algorithms, AppliedMath, Computation, Mathematics, Symmetry, Sci, Applied Sciences
Intelligent Optimization Algorithm: Theory and Applications, 2nd Edition
Topic Editors: Shi Cheng, Chaomin Luo, Shangce GaoDeadline: 31 March 2027
Topic in
Electronics, Modelling, Robotics, Sensors, Virtual Worlds, Applied Sciences, Computation
Intelligent Systems and Immersive Technologies for Human–Machine Interaction and Collaboration
Topic Editors: Vassilis Charissis, Dimitris Drikakis, Mónica Ballesta GaldeanoDeadline: 31 July 2027
Topic in
Algorithms, Computation, Entropy, Mathematics, Fractal Fract, MCA, Symmetry, Dynamics
Dynamics Modeling, Chaos Theories and Nonlinear Control of Complex Systems: Complexity and AI-Driven to Hybrid and Distributed Computing Approaches
Topic Editors: António Lopes, Yeliz Karaca, Sergio Adriani DavidDeadline: 31 August 2027
Conferences
Special Issues
Special Issue in
Computation
Computational Social Science and Complex Systems—2nd Edition
Guest Editors: Minzhang Zheng, Pedro ManriqueDeadline: 30 September 2026
Special Issue in
Computation
Sentiment-Driven Modelling in Business, Economics, and Social Sciences
Guest Editor: Roman MakarovDeadline: 30 September 2026
Special Issue in
Computation
Computational Market Design and Matching in Socio-Technical Systems
Guest Editors: Arnaud Z. Dragicevic, Sinan ErtemelDeadline: 31 October 2026
Special Issue in
Computation
Advances in Healthcare Remote Monitoring Systems and Biomechanical Data-Driven Approaches
Guest Editor: Luis Pastor Sánchez-FernándezDeadline: 31 October 2026