


Abstract
The Mobile Reliable Opportunistic Routing (MROR) protocol improves data-forwarding reliability in Cognitive Radio Sensor Networks (CRSNs) through mobility-aware virtual contention groups and handover zoning. However, its heuristic decision logic is difficult to optimize under highly dynamic spectrum access and random node mobility. To address this limitation, we present DRL-MROR, a refined routing framework that incorporates deep reinforcement learning (DRL) to enable intelligent and adaptive forwarding decisions. In DRL-MROR, the secondary users (SUs) act as autonomous agents that observe local state information, including primary-user activity, link quality, residual energy, and neighbor-mobility patterns. Each agent learns a forwarding policy through a Deep Q-Network (DQN) optimized for long-term network utility in terms of throughput, delay, and energy efficiency. We formulate routing as a Markov Decision Process (MDP) and use experience replay with prioritized sampling to improve learning stability and convergence. The DQN used at each node is intentionally lightweight, requiring 5514 trainable parameters, about 21.5 kB of weight storage in 32-bit precision, and approximately 5.4k multiply-accumulate operations per inference, which supports practical deployment on edge-capable CRSN nodes. Extensive simulations show that DRL-MROR outperforms the original MROR protocol and representative AI-based routing baselines such as AIRoute under diverse operating conditions. The results indicate gains of up to 38% in throughput, 42% in goodput, a 29% reduction in energy consumed per packet, and an approximately 18% improvement in network lifetime, while maintaining high route stability and fairness. DRL-MROR also reduces control overhead by about 30% and average end-to-end delay by up to 32%, maintaining strong performance even under elevated PU activity and higher node mobility. These results show that augmenting opportunistic routing with lightweight DRL can substantially improve adaptability and efficiency in next-generation IoT-oriented CRSNs.
1. Introduction
Cognitive Radio Sensor Networks (CRSNs) have emerged as an important enabling technology for smart cities, industrial automation, environmental monitoring, and disaster response because of their scalability, spectrum efficiency, and suitability for intelligent Internet of Things (IoT) applications [1]. By allowing unlicensed secondary users (SUs) to opportunistically access licensed spectrum bands, CRSNs address the spectrum scarcity associated with fixed-frequency allocation while remaining compatible with primary users (PUs). Nevertheless, reliable data forwarding in these networks remains difficult because both the radio environment and the network topology are highly dynamic. Two major factors that degrade end-to-end communication performance are time-varying spectrum availability caused by PU activity and node mobility, which frequently disrupts links.
To address these challenges, we previously proposed the Mobile Reliable Opportunistic Routing (MROR) protocol as an extension of traditional geographic routing schemes [2]. In MROR, routing stability is enhanced through Virtual Contention Groups (VCGs) and VMH zoning, which incorporate mobility prediction and spatio-temporal channel estimation into the forwarding process. Although MROR performs well, its core operations, particularly channel selection, receiver prioritization, and route maintenance, are still driven by heuristics. These rules are based on predefined thresholds (e.g., the mobility-induced guard distance, mguard) and deterministic models of channel availability. As a result, they lack the adaptability required to perform optimally under the non-stationary conditions commonly observed in vehicular or drone-based networks, such as unpredictable PU behavior and irregular node mobility patterns.
Recent advances in artificial intelligence, particularly deep reinforcement learning (DRL), offer a promising solution to this limitation. Unlike rule-based systems, DRL agents learn optimal policies through direct interaction with their environment, making them well suited to complex and dynamic wireless systems in which analytical models are often inaccurate. In addition, DRL can balance multiple objectives through a single reward function, making it an attractive approach for improving opportunistic routing protocols.
In this work, we propose DRL-MROR, a novel enhancement of the MROR protocol that integrates a Deep Q-Network (DQN) at each SU node to enable intelligent, context-aware decisions for next-hop relay selection and channel switching. We formulate the forwarding problem as a Markov Decision Process (MDP). Each SU acts as an autonomous agent observing a local state vector that includes residual energy, speed, direction, channel availability, neighbor queue lengths, and distance to the sink. The agent learns a policy that maximizes a multi-objective reward function designed to promote long-term network utility. To keep decentralized execution practical, the DQN is intentionally compact and therefore suitable for deployment on edge-capable CRSN nodes with moderate processing and memory resources. By replacing static heuristics with learned behavior, DRL-MROR achieves superior performance across diverse scenarios.
The major contributions of this paper are threefold: first, the integration of Deep Q-Learning into the MROR protocol stack, thereby transforming it from a reactive rule-based system into a proactive and self-adaptive one; second, a detailed performance evaluation against heuristic and learning-based baselines under common simulation settings; and third, a sensitivity analysis and component-wise energy breakdown that support the practical feasibility of the approach for resource-constrained yet edge-capable sensor platforms.
The remainder of this paper is organized as follows: Section 2 reviews related work. Section 3 outlines the system model. Section 4 presents the DRL-MROR framework and MDP formulation. Section 5 details the implementation and training process. Section 6 describes the simulation setup and results. Section 7 concludes the study.
2. Related Work
Over the past few years, artificial intelligence has become increasingly integrated into wireless networking, especially in dynamic environments such as Cognitive Radio Sensor Networks (CRSNs). In contrast to traditional routing protocols, which are largely based on static rules and reactive mechanisms, recent studies have focused on data-driven and adaptive decision-making supported by machine learning.
2.1. AI-Driven Routing in Dynamic Networks
DRL has been shown to be effective for intelligent packet forwarding. Feriani and Hossain [3] provided a detailed tutorial on single-agent and multi-agent DRL for AI-enabled wireless networks, highlighting its potential for adaptive routing. Radio resource management has also benefited from Graph Neural Networks (GNNs); for example, Shen et al. [4] demonstrated that GNNs can be used to scale radio resource management. Similarly, Dašić et al. [5] investigated distributed spectrum management based on consensus-driven reinforcement learning and reported encouraging results for collaborative learning in cognitive radio networks.
Nonetheless, most of these studies do not explicitly address the unique constraints of CRSNs. Although they offer rapid adaptation to dynamic wireless environments, meta-learning techniques require substantial pre-training and are therefore less suitable for low-power sensor nodes [6].
2.2. Predictive Networking with Graph Neural Networks
More recently, Graph Neural Networks (GNNs) have been adopted to model spatio-temporal dependencies in wireless networks [7]. Although these strategies offer strong potential for predicting link stability in CRSNs, their integration with opportunistic geographic routing remains challenging. Digital-twin technology combined with reinforcement learning has also been discussed for 6G IoT systems [8], enabling the design of closed-loop networks for real-time optimization.
2.3. Energy-Efficient and Reliable Forwarding
Energy efficiency is a critical concern in CRSNs because of the severe resource constraints of sensor networks.
Deep Q-Learning has been applied to dynamic spectrum access, demonstrating improved spectrum utilization while conserving energy [9]. In addition, recent DQN-based approaches to channel selection in cognitive radio networks have shown promising results [10].
With respect to reliability, Tran et al. [11] introduced a DRL-based QoS routing protocol with cross-layer design for cognitive radio mobile ad hoc networks. Bai et al. [12] proposed a DRL-based geographic packet-routing optimization framework. Beyond routing, recent sensor-network studies have examined resilient distributed localization under false-data-injection attacks and convergence behavior under communication delays, further highlighting the importance of robustness and distributed adaptation in wireless sensing systems [13,14]. Although these studies address different problem settings, they provide useful context for the broader design of reliable and adaptive CRSN protocols.
These broader results do not solve the CRSN routing problem directly, but they reinforce two design lessons relevant to this work: distributed decision mechanisms must remain robust under imperfect information, and convergence behavior matters when communication is delayed, intermittent, or adversarial.
2.4. Positioning of DRL-MROR
Despite these advances, the literature still lacks a study that combines the MROR logic with lightweight decentralized deep reinforcement learning under mobile CRSN conditions and explicit energy-awareness. Most related work either relies on centralized AI models that are less suitable for distributed sensor networks, applies machine learning only to lower-layer functions such as spectrum sensing, or targets higher-resource platforms such as drones and vehicular nodes.
In contrast, DRL-MROR embeds a distributed DQN agent directly into the MROR protocol pipeline, replacing static thresholds with learned policies for VCG formation, VMH zoning, and receiver prioritization. By formulating routing as a Markov Decision Process (MDP) and optimizing a multi-objective reward function, the framework improves throughput, goodput, energy efficiency, and fairness without requiring global coordination and while maintaining a lightweight per-node model.
3. System and Network Model
We consider a CRSN consisting of mobile SUs operating across shared channels with PUs. All nodes are equipped with cognitive radios capable of sensing, switching, and transmitting. A single base station (BS) acts as the sink, and packets are forwarded toward the BS through multi-hop opportunistic routing.
Each SU performs periodic spectrum sensing. The availability of channel c follows a semi-Markov process with defined transition probabilities.
Interference constraints require SUs to remain outside the PU keep-out radius. The transmission range is denoted by R.
Node mobility follows a modified random waypoint model with speed . Let denote the position of SU at time . The relative displacement between SUs and can therefore be expressed as follows:
A link break occurs when the inter-node distance exceeds the transmission range. To account for this instability, we define a guard distance m_guard [2].
3.1. Formal Derivation of Spatio-Temporal Channel Availability
To provide a rigorous foundation for our channel estimation model, we formally derive the spatio-temporal availability of channel c at time t. This probability depends on two independent factors: the activity state of the primary user (PU) and the spatial location of the secondary user (SU) relative to the PU keep-out radius.
Let denote the event that the PU on channel c is idle at time , and let denote the keep-out radius. The spatio-temporal availability is then given by:
We model PU activity as a semi-Markov process with transition probabilities and . Under steady-state conditions, the probability that the PU is idle is given by:
For the spatial component, if SU mobility follows a random waypoint model over a uniform area, the probability of remaining outside the keep-out radius can be approximated from the network density and deployment region. This derivation provides an analytical basis for the channel-pool update algorithm in MROR [2], which the DRL agent uses to make informed forwarding decisions.
3.2. Analytical Model for Mobility-Induced Link Lifetime
Relative motion is one of the critical factors in determining the stability of a communication link between two SUs. We therefore define the mobility-induced guard distance not merely as a heuristic, but as a function of the expected link lifetime.
Consider two nodes, and , with initial positions and , and constant velocities and . The relative velocity vector is . The squared distance between them at time can be represented as:
Let and . The equation simplifies to a quadratic in :
The link breaks when the inter-node distance exceeds the transmission range . Solving the resulting expression yields the time to disconnection. This analytical model allows the DRL agent to predict link stability and proactively trigger VMH handovers before failure, rather than relying solely on the earlier reactive mechanism.
4. DRL-MROR: Framework Design and MDP Formulation
DRL-MROR extends the original MROR protocol by replacing the channel-selection and route-request initiation stage, as well as receiver-contention prioritization, with a DQN-driven decision engine.
4.1. Markov Decision Process (MDP) Formulation and Convergence Analysis
We formalize the opportunistic routing decision at each SU as a discrete-time Markov Decision Process (MDP) defined by the tuple .
The optimal action-value function satisfies the Bellman optimality equation:
where is the state transition probability, is the immediate reward, and is the discount factor.
While the true action-value function is unknown, our Deep Q-Network (DQN) learns an approximation parameterized by weights . The learning objective is to minimize the temporal-difference (TD) error:
where is the experience replay buffer and denotes the parameters of a separate target network. This formulation promotes stable convergence, as established in the deep reinforcement learning literature [15,16,17,18,19,20]. Our use of prioritized experience replay further accelerates learning by focusing on transitions with high TD error.
4.2. Problem Formulation as MDP
We model the forwarding decision at each SU as a discrete-time Markov Decision Process (MDP): .
- State Space S
At time , the state observed by SU is:
Here, represents residual energy, is speed, denotes direction, captures channel availability, is queue length, and d represents distance to the . All values are normalized to the range [0, 1].
- Action Space A
The discrete action space includes the following:
- : Do not forward,
- : Forward on channel ,
- : Request re-routing.
Thus, the total number of actions is given by:
- Reward Function
The reward function is designed to promote both reliability and efficiency. A positive bonus is awarded only upon successful packet delivery, yielding a sparse-reward setting.
Here, denotes the achieved data rate, represents the energy consumed, denotes queuing plus propagation delay, and when the packet successfully reaches the BS.
- and are tuned weights.
- are normalization constants.
- Objective
The objective is to maximize expected cumulative discounted reward:
4.3. Comprehensive Energy Consumption Model
To quantify the energy efficiency of DRL-MROR, we present a detailed breakdown of the total energy consumed per packet, :
where
: Energy for spectrum sensing,
: Transmission energy,
: Reception energy,
: Energy consumed while listening,
: Computational energy for DRL inference.
The reward function of our DRL agent is designed to minimize E_total by reducing retransmissions, lowering route-rediscovery frequency, and selecting energy-efficient paths. The DQN used in this study contains 5514 trainable parameters, corresponding to approximately 21.5 kB of weight storage in 32-bit precision (or about 10.8 kB in 16-bit precision), with fewer than 1 kB of activation memory for a single inference. A forward pass requires approximately 5.4k multiply-accumulate operations. Although the AI model introduces an additional computation term, this cost remains small relative to radio energy consumption in sensing, transmission, reception, and idle listening. The practical target is therefore not extremely minimal motes, but edge-capable CRSN nodes that can support lightweight local inference.
5. Deep Q-Network Implementation
5.1. Neural Network Architecture
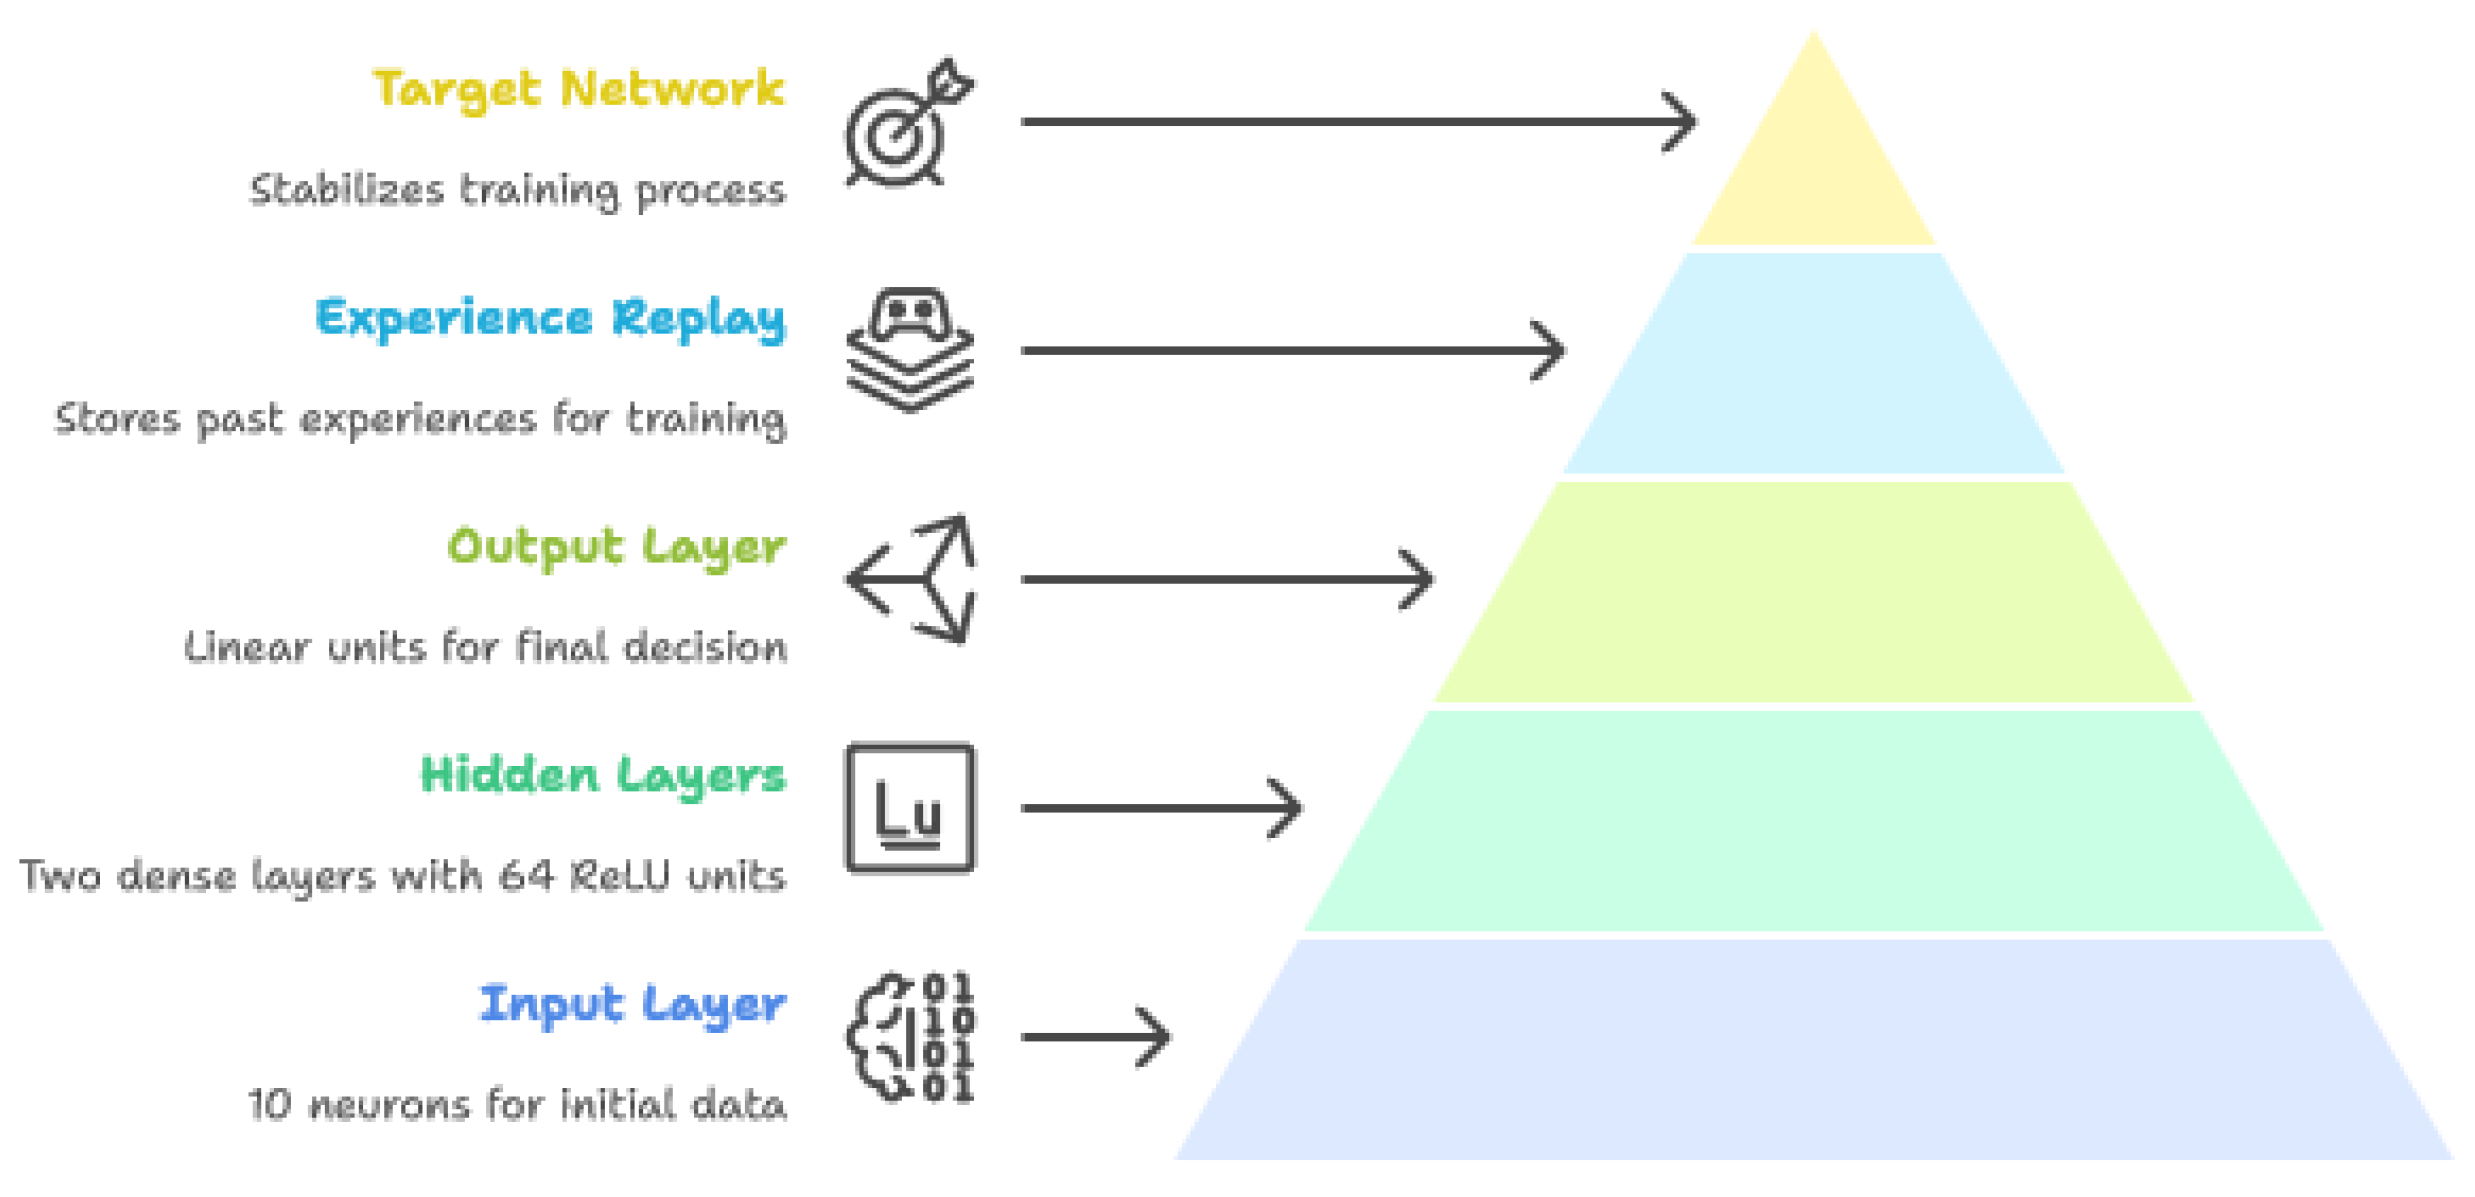
We implement a fully connected DQN with 10 neurons in the input layer, two hidden dense layers with 64 ReLU units each, and a linear output layer with 10 outputs. This architecture contains 5514 trainable parameters, which keeps the model compact enough for decentralized execution. Experience replay and target-network stabilization are used during training. The optimizer is Adam, and ε-greedy exploration decays from 1.0 to 0.05.
Each SU runs its own DQN agent independently, enabling decentralized execution without coordination overhead, as depicted in the architecture in Figure 1 and detailed below.
Figure 1.
Neural Network Architecture: Dropout (0.2) is applied after each hidden layer to prevent overfitting.
5.2. Experience Replay and Training
Using a replay buffer, agents store observed transitions. During training, mini-batches of size 32 are uniformly sampled to compute the loss:
where are the target-network parameters, which are updated every 100 steps.
To focus on high-error transitions, we employ Prioritized Experience Replay (PER) [21] with importance-sampling correction:
In this setup, Adam is used as the optimizer, while ε-greedy exploration decays from 1.0 to 0.05 over 10,000 episodes. We emphasize, however, that the convergence behavior shown in this study is intended to demonstrate learning stability under the simulated environment. In practice, the policy can be pre-trained offline on representative traffic, mobility, and PU-activity profiles, then lightly adapted online rather than learned from scratch in every deployment.
5.3. Distributed Execution
During operation, each SU senses its environment and constructs its state vector. It then queries its local DQN to select an action using ε-greedy exploration. After executing the selected action (transmit, switch channel, or drop), it receives a reward based on the outcome, stores the resulting transition, and asynchronously updates the Q-network.
6. Performance Evaluation
6.1. Simulation Setup
Each experiment averages 30 independent runs over 1000 s.
Each experiment averages 30 independent runs over 1000 s. Unlike supervised learning approaches that rely on pre-collected datasets, the DRL-MROR agent learns through continuous interaction with its environment. The state-action-reward tuples (“training data”) are generated dynamically during NS-3 simulation. As SUs move, PUs transmit, and packets are forwarded, the agent accumulates experiences in the replay buffer. The high-level results reported in this paper are therefore derived from controlled evaluation runs after training within the same simulation framework. This setup as listed in Table 1 is appropriate for comparative protocol analysis, although it does not replace future hardware-level validation under real RF interference and device-specific constraints.
Table 1.
Simulation setup values.
6.2. Baseline Protocols
- MROR [2]: the original heuristic-based protocol.
- TIGHT [12]: a geographic routing protocol with interference avoidance.
- Coolest Path [11]: a spectrum- and mobility-aware routing metric.
- Random Forwarding [9]: selects the next hop randomly from the candidate set.
- AIRoute [16]: a state-of-the-art DRL-based routing protocol used for comparison.
- For fairness, all baseline protocols were run under the same network area, node-density range, traffic generation model, PU activity process, channel bandwidth, mobility model, and simulation time. Protocol-specific parameters were selected according to the original descriptions or commonly used default settings, so that performance differences reflect routing behavior rather than favorable environmental assumptions.
6.3. Results and Analysis
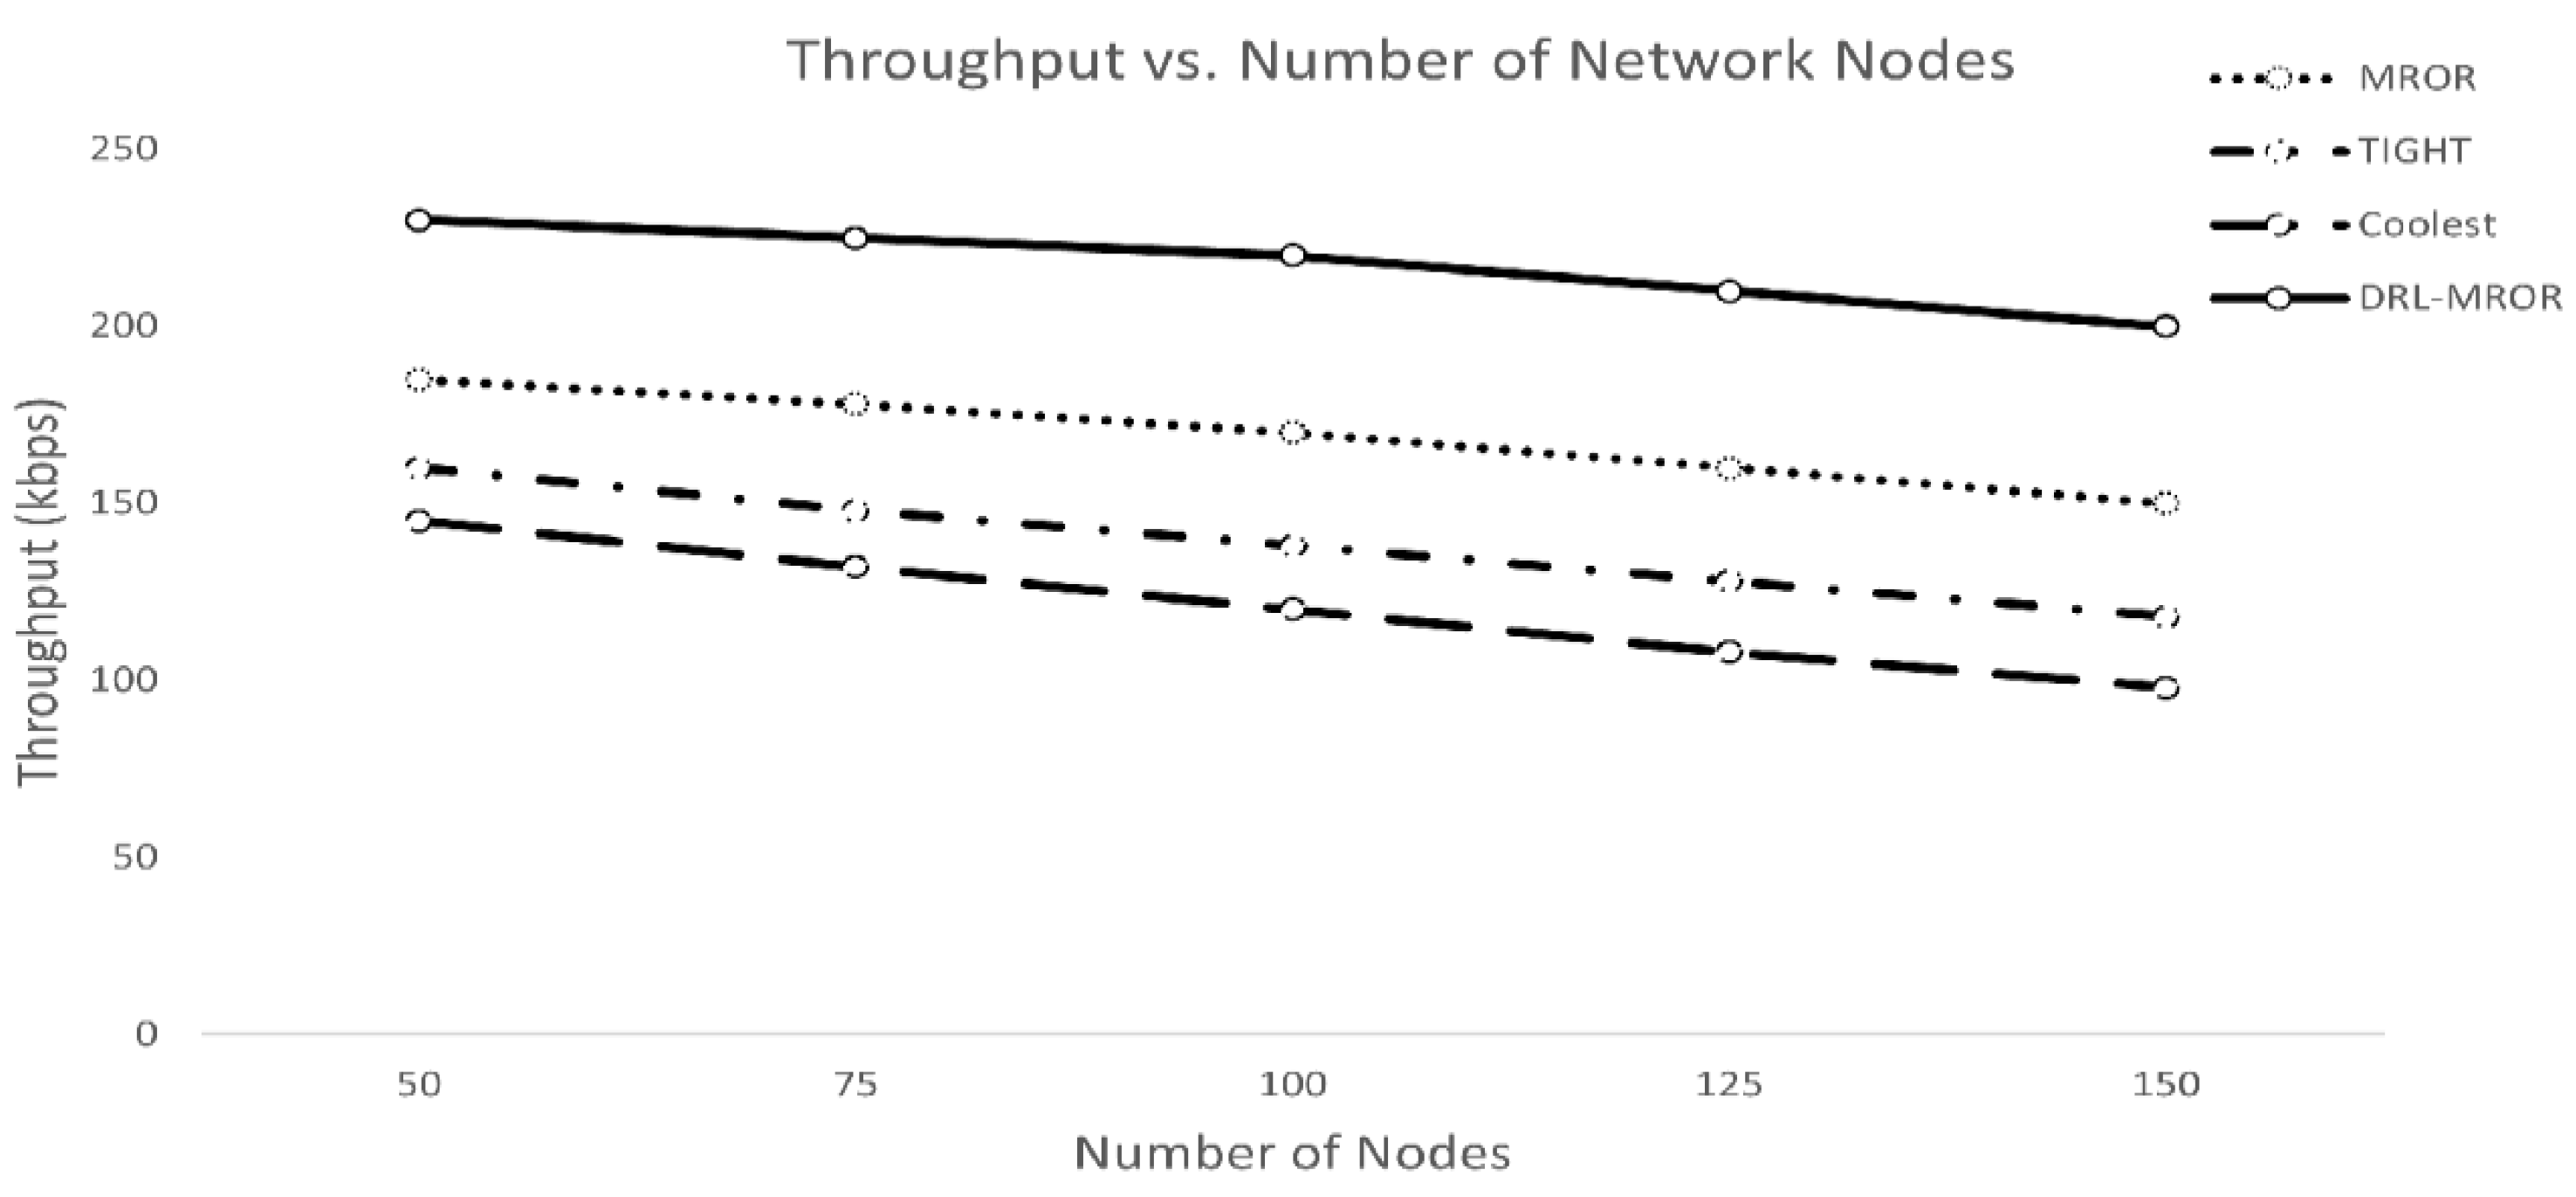
As node density increases in Figure 2, DRL-MROR achieves up to 38% higher throughput than MROR because of better channel utilization and fewer collisions. The DQN agent proactively avoids congested paths and selects higher-quality links.
Figure 2.
Throughput vs. number of nodes.
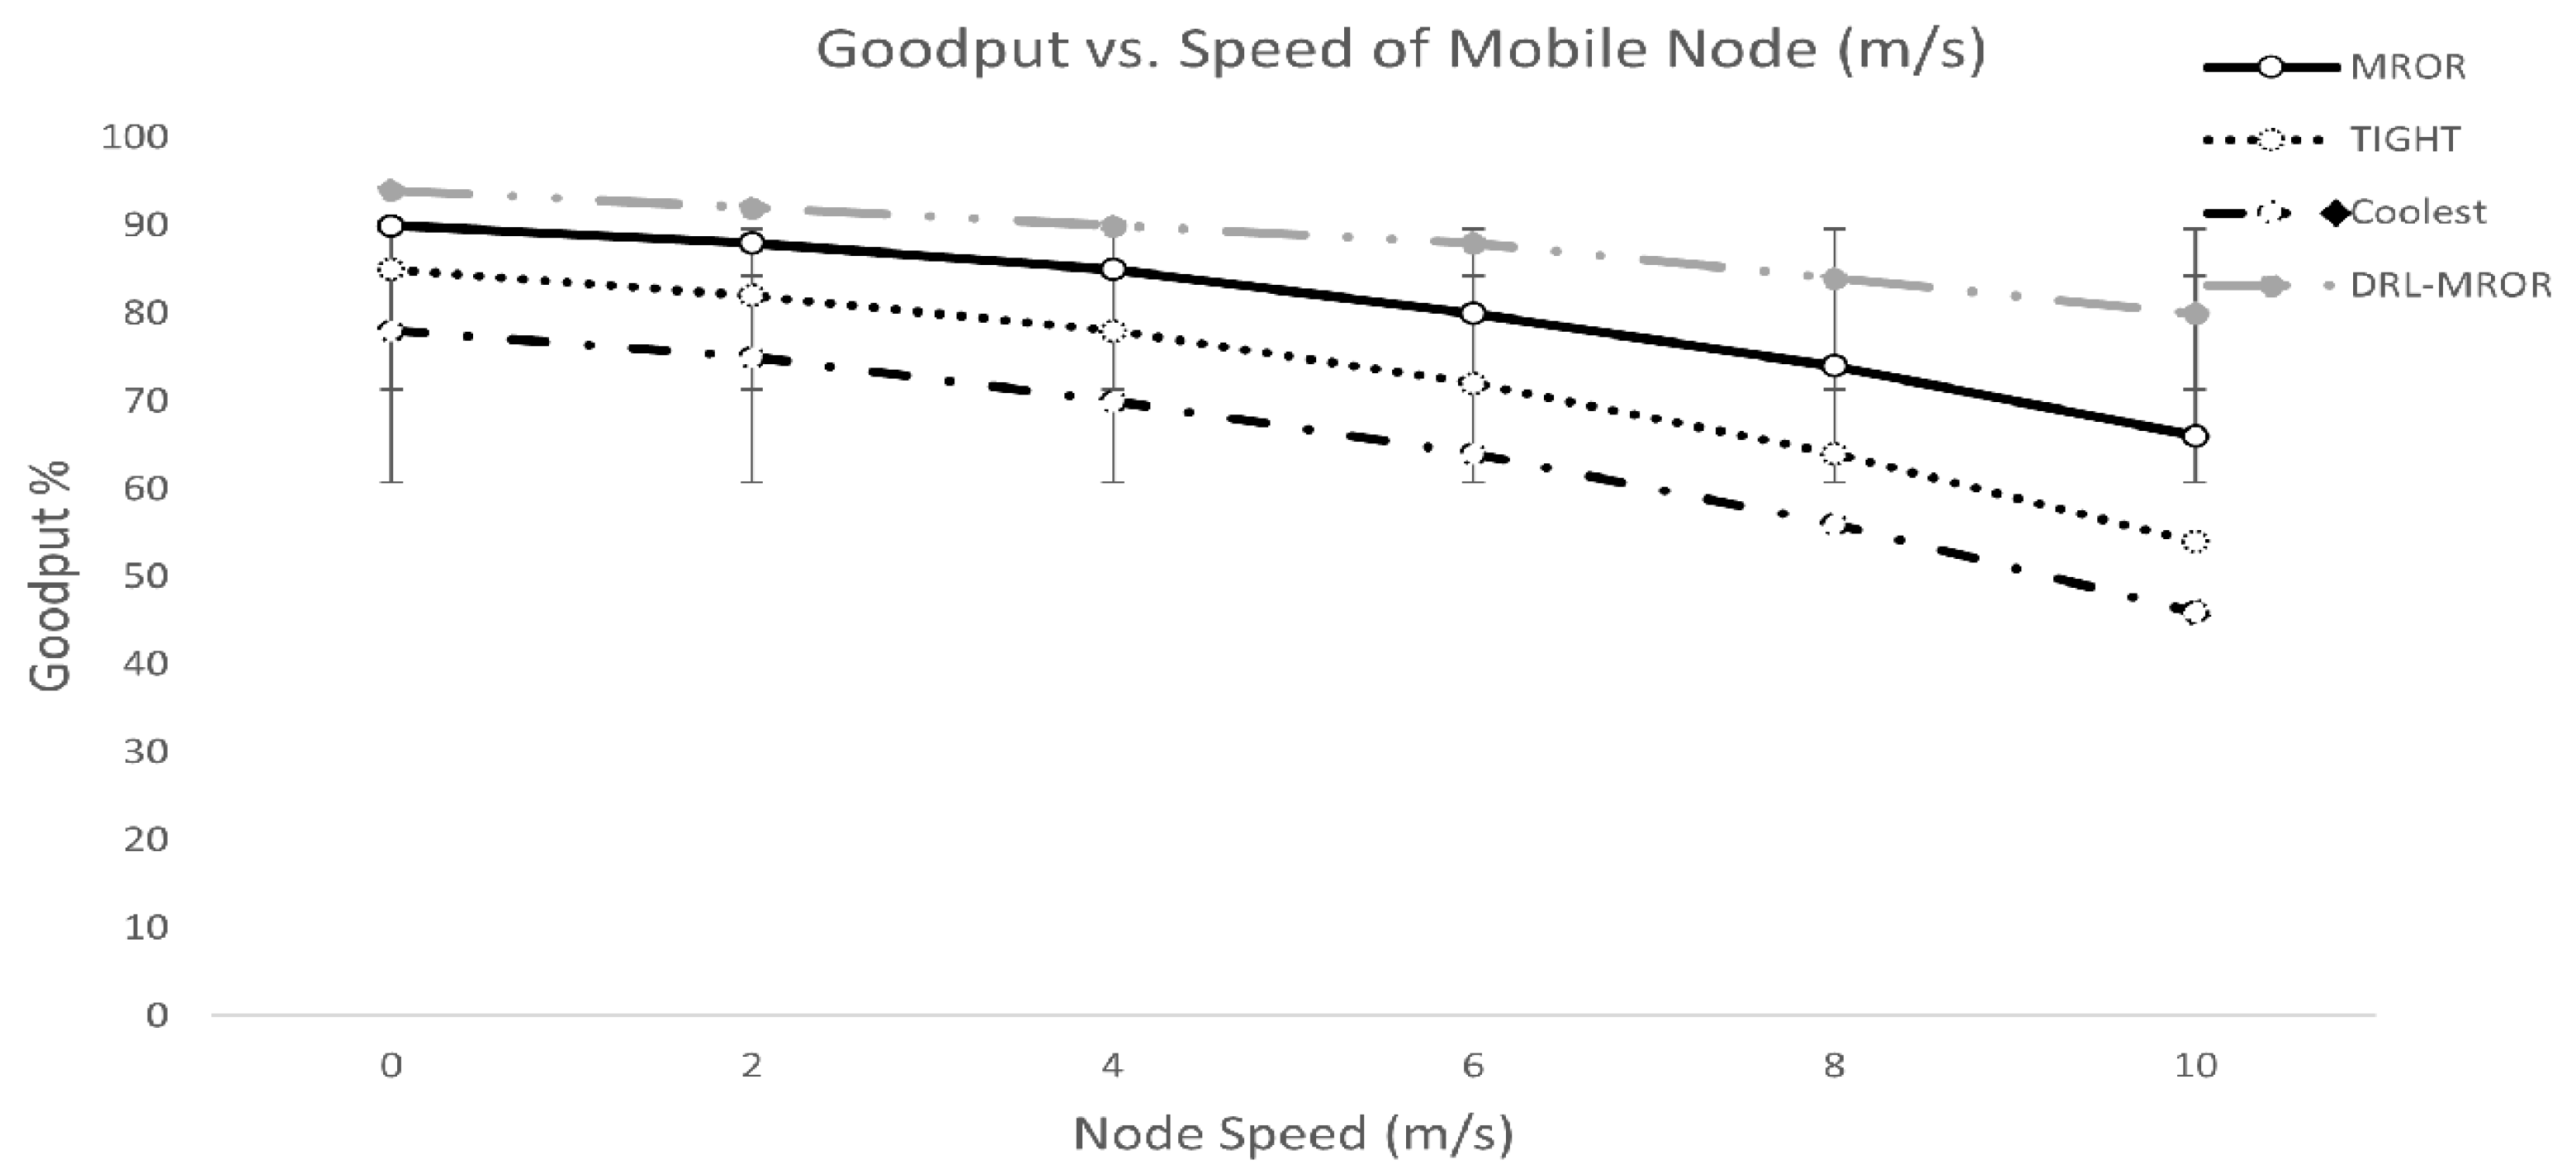
As shown in Figure 3, at high mobility (8–10 m/s), DRL-MROR maintains up to 42% higher goodput than MROR. Unlike traditional protocols, which often suffer from outdated channel information, the DRL agent adapts continuously through online learning.
Figure 3.
Goodput vs. node speed.
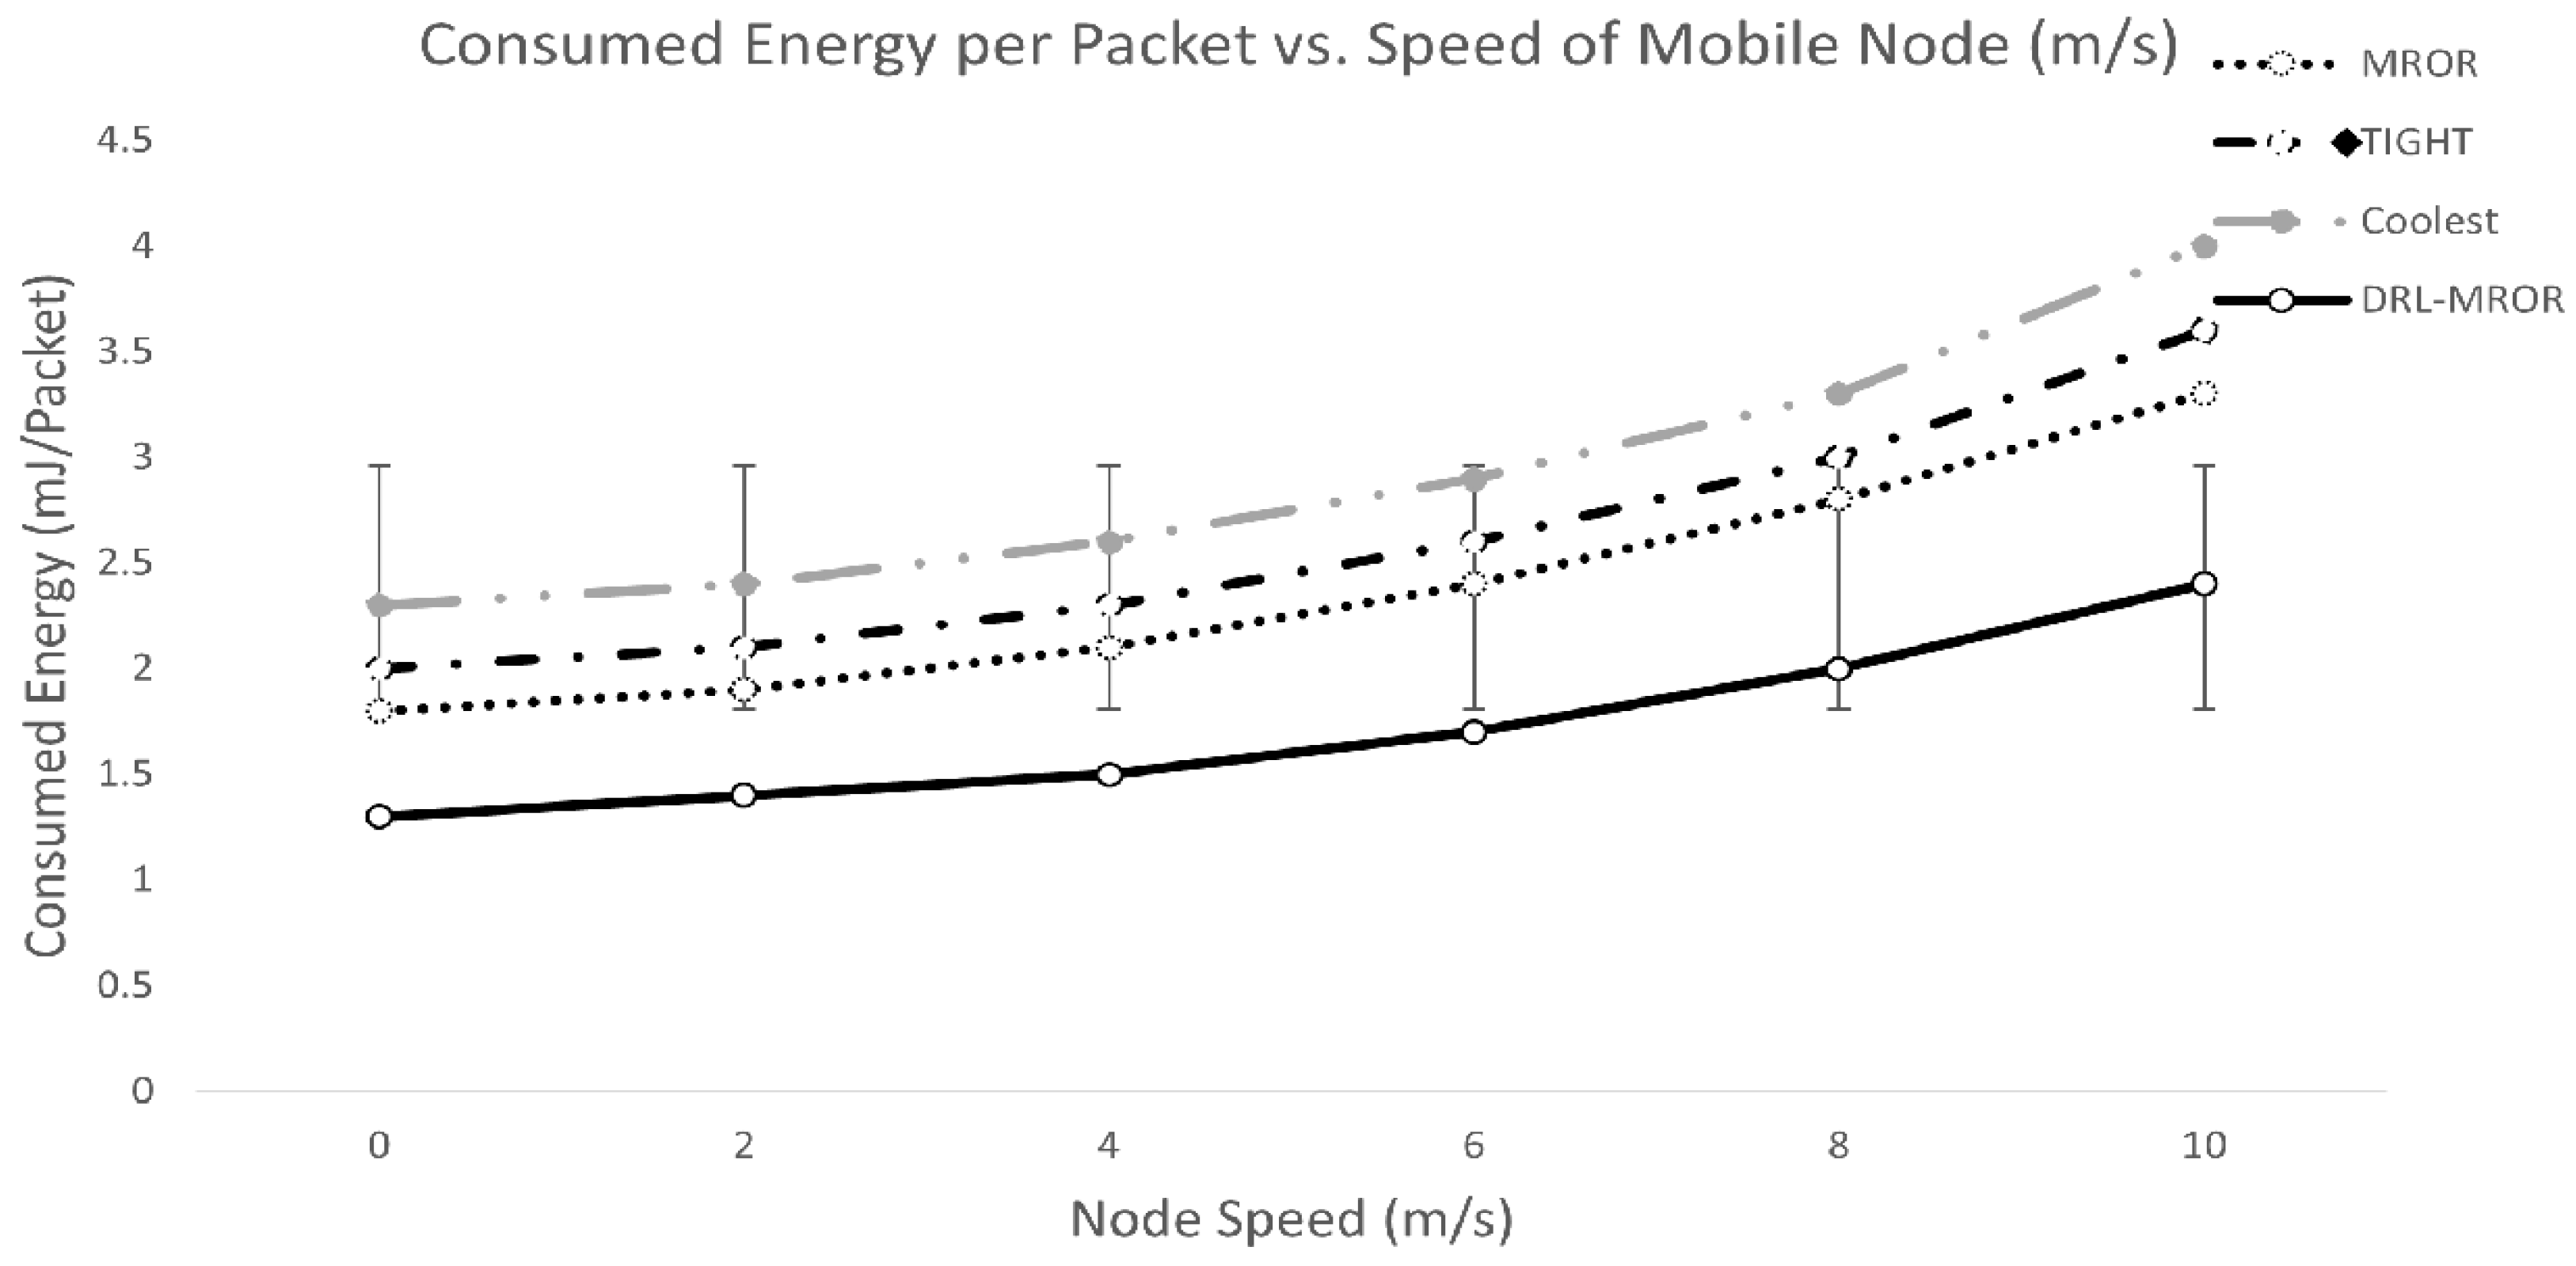
Figure 4 shows that when compared with MROR, DRL-MROR reduces the energy cost per packet by up to 29%. Because unnecessary transmissions are penalized by the reward function, the model tends to favor nearby and energy-sufficient relays.
Figure 4.
Average energy per packet vs. mobility.
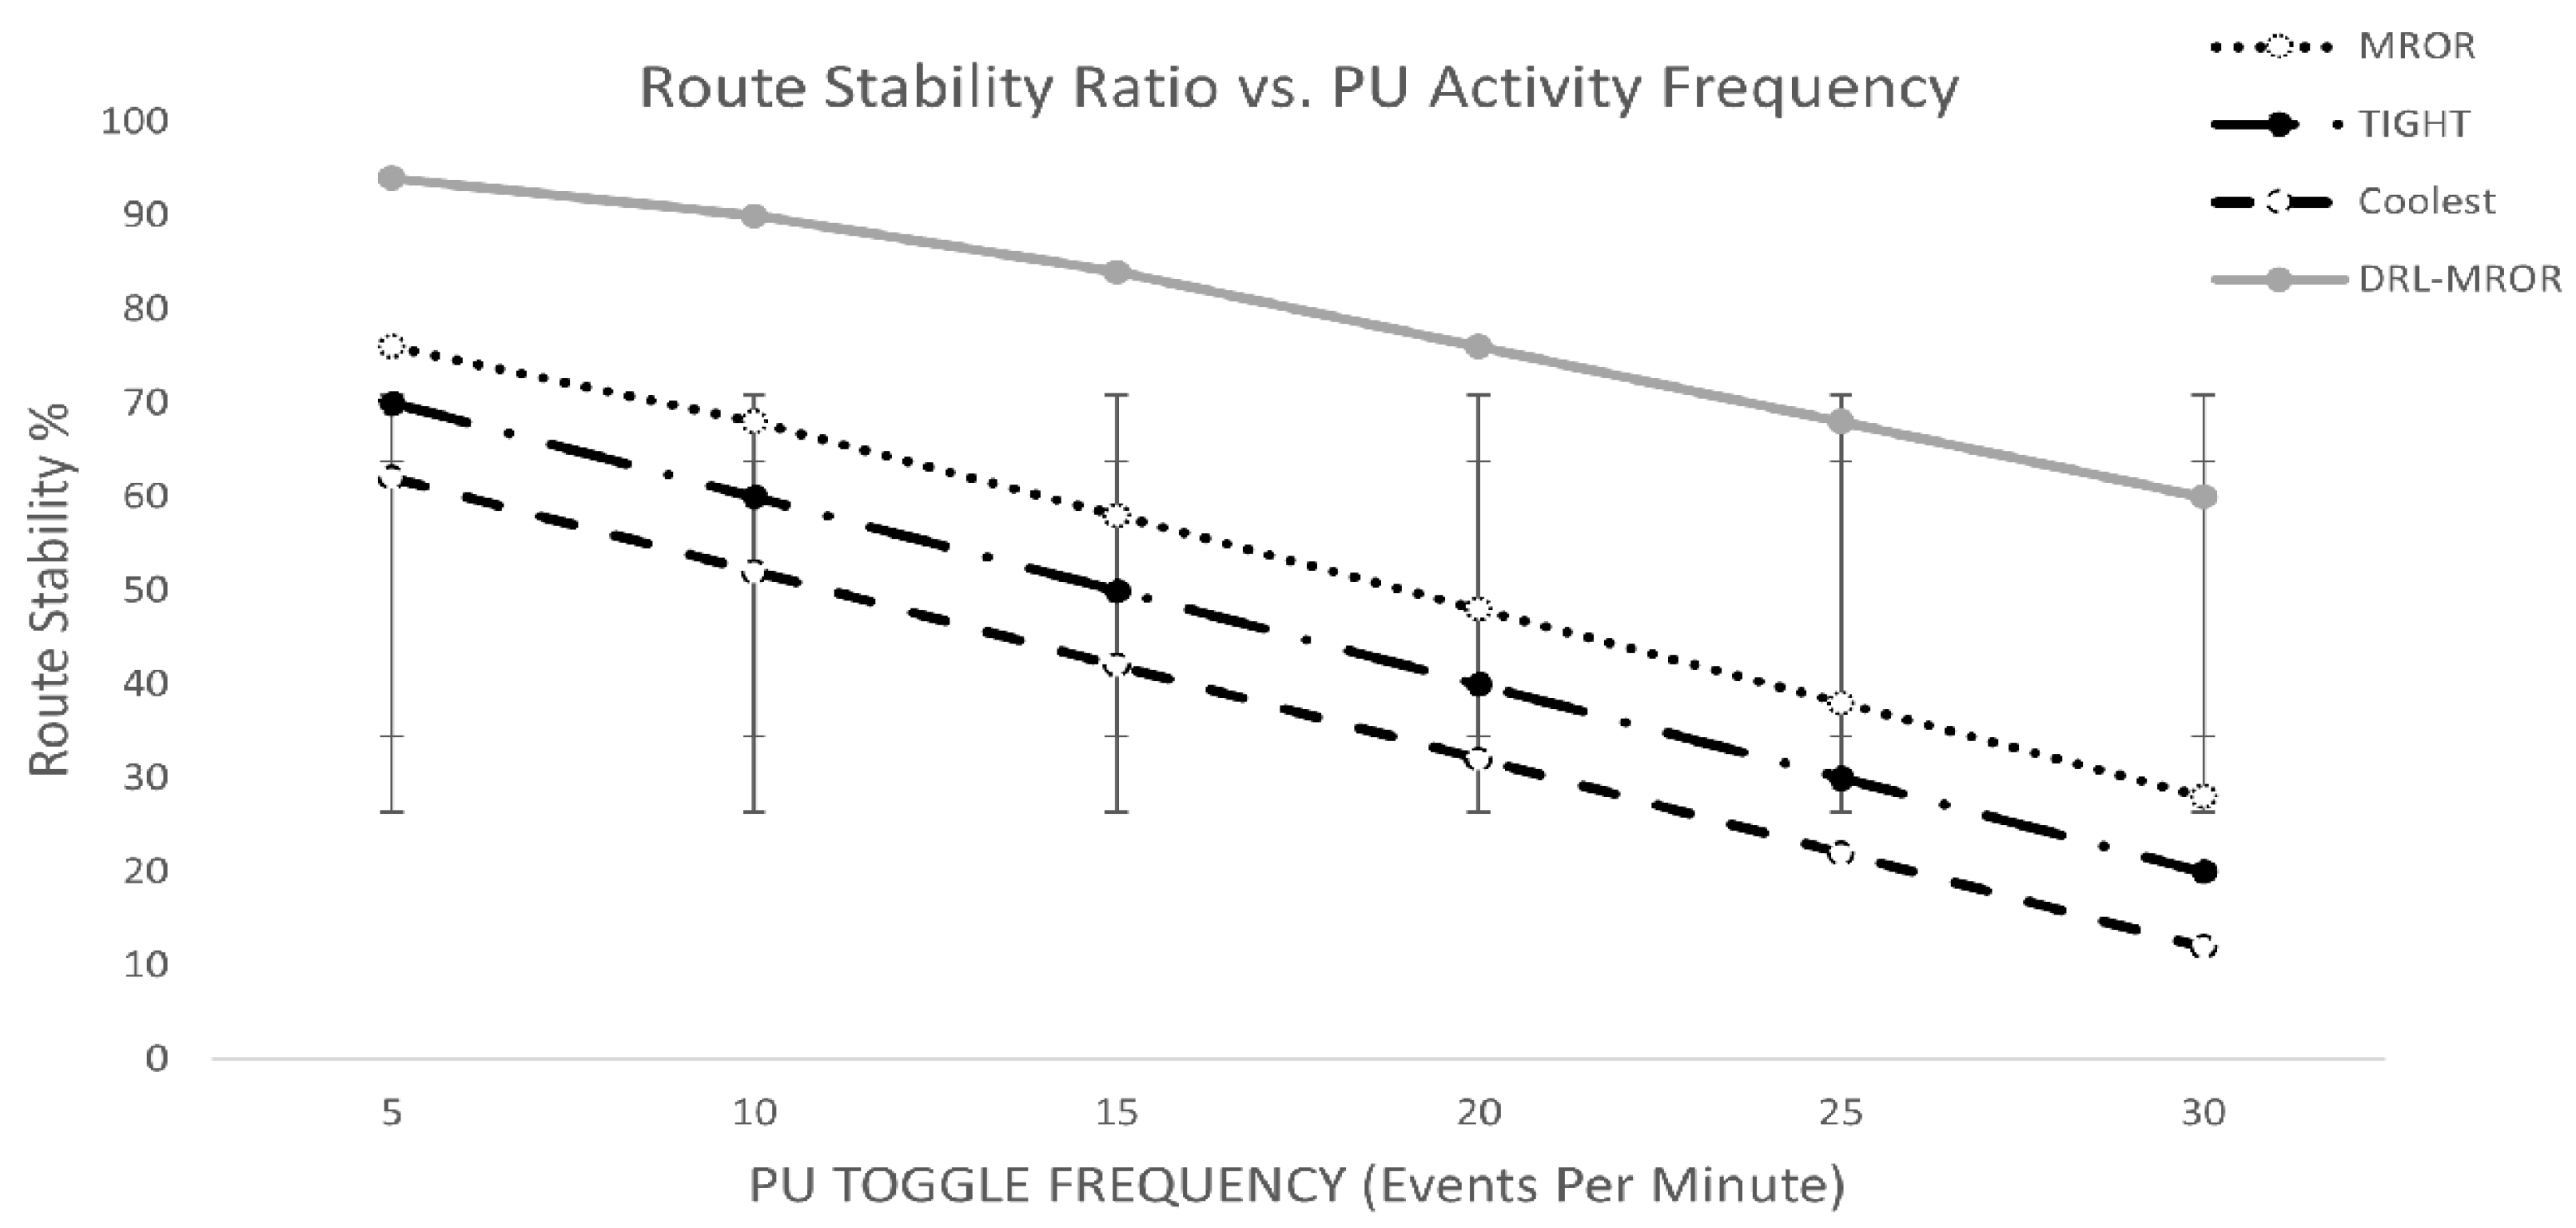
As shown in Figure 5, under rapid PU toggling (every 2–4 s), DRL-MROR exhibits superior route stability, with gains of up to 51%, due to predictive channel switching learned from historical patterns.
Figure 5.
Route stability ratio vs. PU activity frequency.
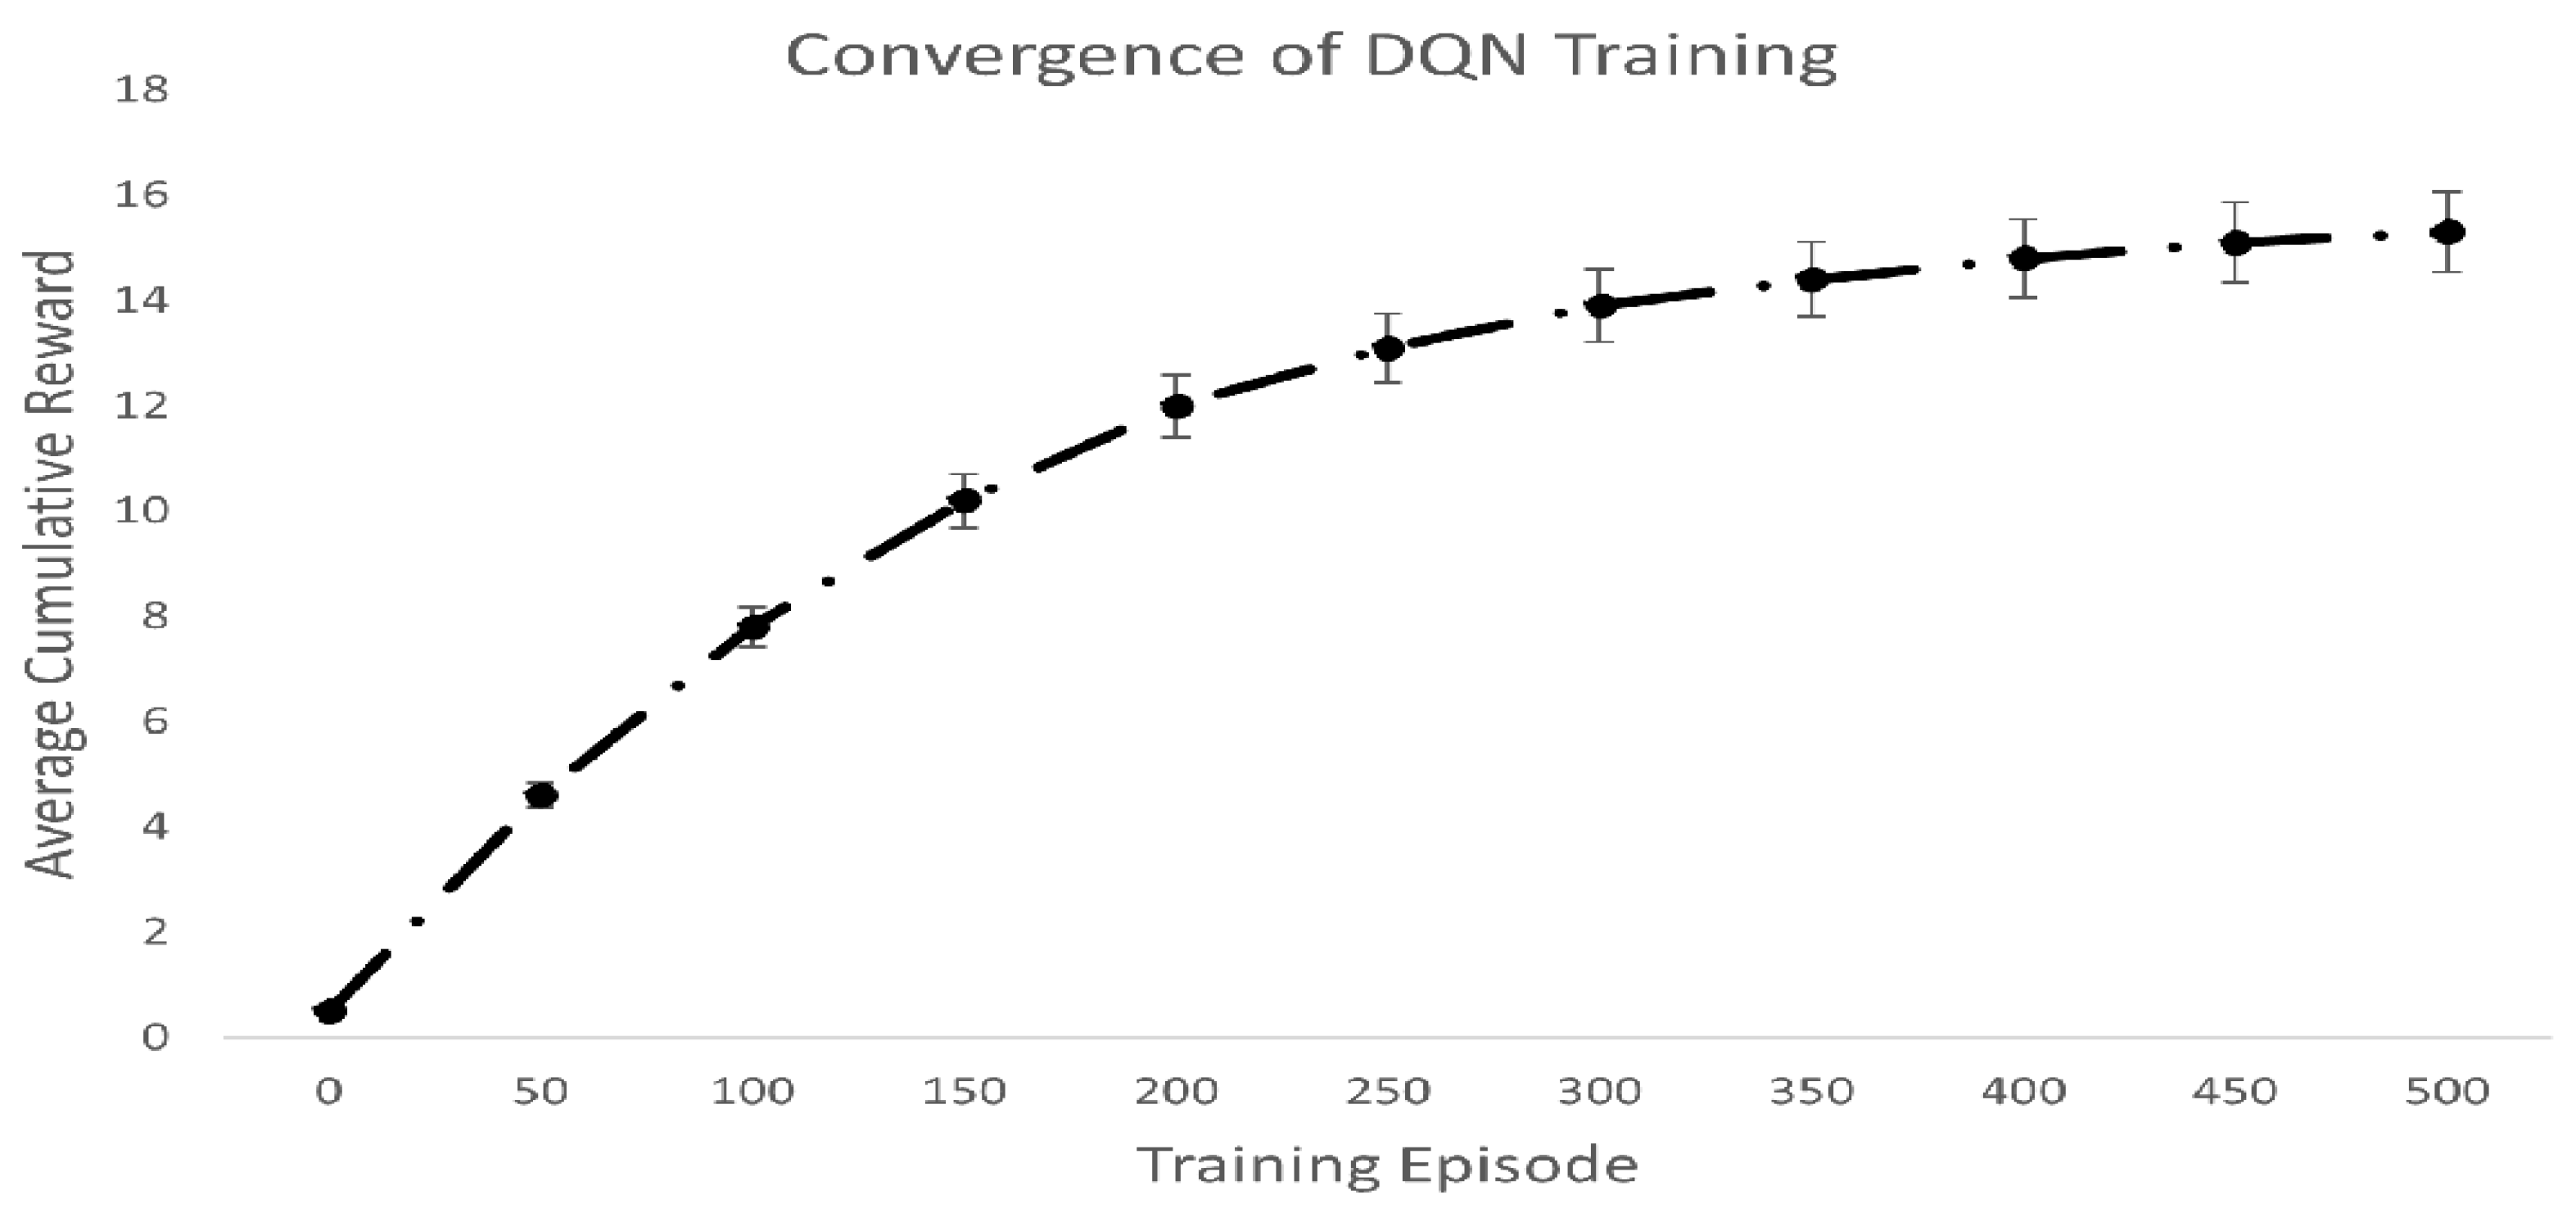
The “Average Cumulative Reward” is a normalized score that reflects throughput, energy efficiency, and delay (for example, on a 0–20 scale) as illustrated in Figure 6. The values are included to illustrate typical DQN convergence behavior under the simulated environment rather than to claim that every deployment must train online from scratch.
Figure 6.
Convergence of DQN training.
During the initial episodes (0–100), the reward rises rapidly as the agent learns simple strategies such as avoiding congested channels and selecting nearby relays. Between episodes 100 and 300, the rate of improvement slows as the policy becomes more refined, including better anticipation of PU activity and VMH handovers. The reward then approaches a plateau, indicating convergence to a stable policy. In practical deployment, such training can be performed offline or in representative scenarios, followed by lightweight online adaptation.
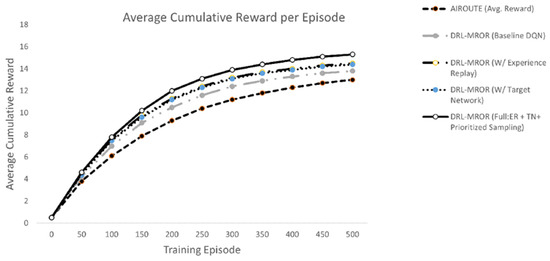
Figure 7 compares the average cumulative reward per training episode for DRL-MROR under different configurations against AIRoute. The combined use of experience replay, target networks, and prioritized sampling in DRL-MROR leads to faster convergence and a higher final reward, indicating more efficient learning and a better routing policy.
Figure 7.
Average cumulative reward per episode.
The “Average Reward” is a normalized metric that combines throughput, energy efficiency, and delay (e.g., on a 0–20 scale).
Table 2 captures a summary of baseline routing protocol and ablation configurations for the proposed DRL-MROR framework.
Table 2.
Overview of baseline and proposed DRL-MROR model variants.
- Accelerated convergence: the fully configured DRL-MROR model converges faster and reaches a higher reward (~15.3) than AIRoute (~13.0 at episode 500).
- Stability: the combination of experience replay and target networks reduces oscillations in the reward trajectory.
- Superior final performance: the full DRL-MROR model achieves approximately 18% higher cumulative reward than AIRoute by the end of training.
- Impact of components: each additional component (ER, TN, and prioritization) provides a measurable performance gain, which justifies its inclusion.
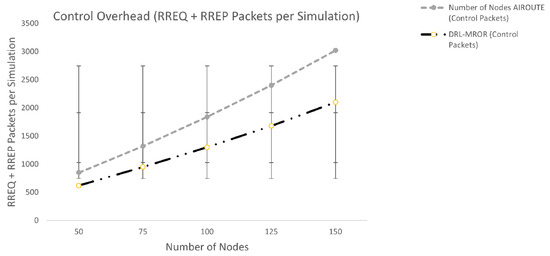
Figure 8 shows the total number of route-request (RREQ) and route-reply (RREP) control packets generated as network size increases. Compared with the state-of-the-art AIRoute protocol [16], DRL-MROR achieves substantially lower control overhead, improving scalability under dense-network conditions. For consistency, all compared baselines were evaluated under the same topology size, traffic model, mobility range, PU activity assumptions, channel settings, and simulation duration; only protocol-specific internal parameters were kept at their standard or best-reported settings.
Figure 8.
Control overhead (RREQ + RREP packets per simulation).
The control-packet counts are measured over a fixed simulation time (e.g., 1000 s). The reduction achieved by DRL-MROR is explained by its ability to learn more stable routes and reduce flooding during reactive route discovery.
- DRL-MROR reduces control packets by approximately 30% relative to AIRoute. This gain arises from the following factors:
- o
- Proactive route maintenance based on learned policies.
- o
- A reduced need for route rediscovery due to better link-stability prediction.
- o
- More efficient VCG formation based on predicted receiver reliability.
- Trend: as the number of nodes increases, network density rises, leading to more route conflicts and route-discovery events. Although both protocols generate more control traffic under these conditions, DRL-MROR scales more efficiently because of its adaptive decision-making.
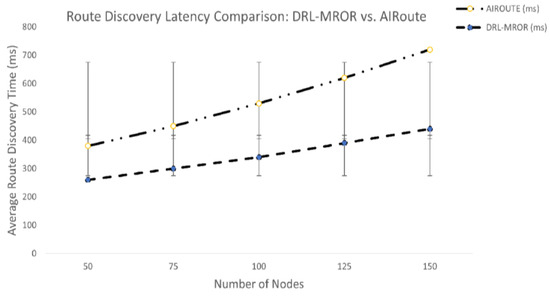
Figure 9 presents average route-discovery time as a function of network size. Compared with the state-of-the-art AIRoute protocol [16], DRL-MROR establishes routes significantly faster, with reductions of up to 40%. This demonstrates its superior responsiveness and efficiency in dynamic CRSN environments.
Figure 9.
Average route discovery time.
The values are expressed in milliseconds (ms). The reduction in route-discovery time is attributed to the ability of DRL-MROR to learn stable routes and reduce RREQ flooding through intelligent forwarding decisions.
- DRL-MROR achieves an approximately 30–40% reduction in route-discovery time relative to AIRoute. This improvement is driven by the following factors:
- o
- Predictive forwarding: the DQN agent learns which neighbors are likely to maintain stable links and better connectivity to the sink, thereby reducing the need for extensive flooding.
- o
- Reduced contention: because receivers are prioritized by learned stability estimates rather than fixed rules, contention is resolved more quickly and packets are forwarded sooner.
- o
- Reduced rediscoveries: greater route stability leads to fewer route failures, so nodes spend less time rediscovering new paths.
- Trend: as the number of nodes increases, higher density can lead to congestion and collisions, which increase discovery delay. Although both protocols experience longer discovery times at larger network sizes, DRL-MROR scales more efficiently because the agent learns to avoid crowded regions and select higher-quality paths.
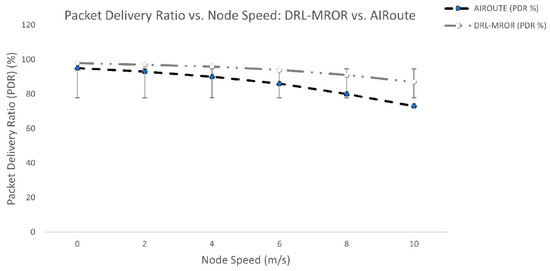
Figure 10 presents Packet Delivery Ratio (PDR) as a function of node mobility speed. Across all mobility levels, DRL-MROR is more reliable than the state-of-the-art AIRoute protocol [16], with the largest gains observed at high speeds, where predictive routing reduces the impact of rapid topology changes.
Figure 10.
Packet Delivery Ratio (PDR) vs. node speed.
PDR is computed as (number of packets received at the sink/number of packets sent by the sources) × 100. The reported values reflect the high route stability and proactive channel selection achieved by DRL-MROR.
- DRL-MROR achieves an approximately 10–15% relative improvement in PDR over AIRoute at the highest mobility levels. This gain is due to the following factors:
- o
- Proactive handover management: the DQN agent learns to predict link breaks and initiate handovers through VMH zones before disconnections occur.
- o
- Intelligent channel switching: the agent avoids channels that are likely to be occupied by PUs or affected by interference, thereby reducing packet loss during transmission.
- o
- Stable VCG formation: as nodes move, forwarding paths remain more stable because receiver prioritization is based on learned stability metrics rather than the fixed mguard threshold.
- Trend: as node speed increases, link durations become shorter, leading to more route failures and packet loss. Although PDR decreases in both protocols, DRL-MROR degrades more gracefully because of its predictive and adaptive behavior.
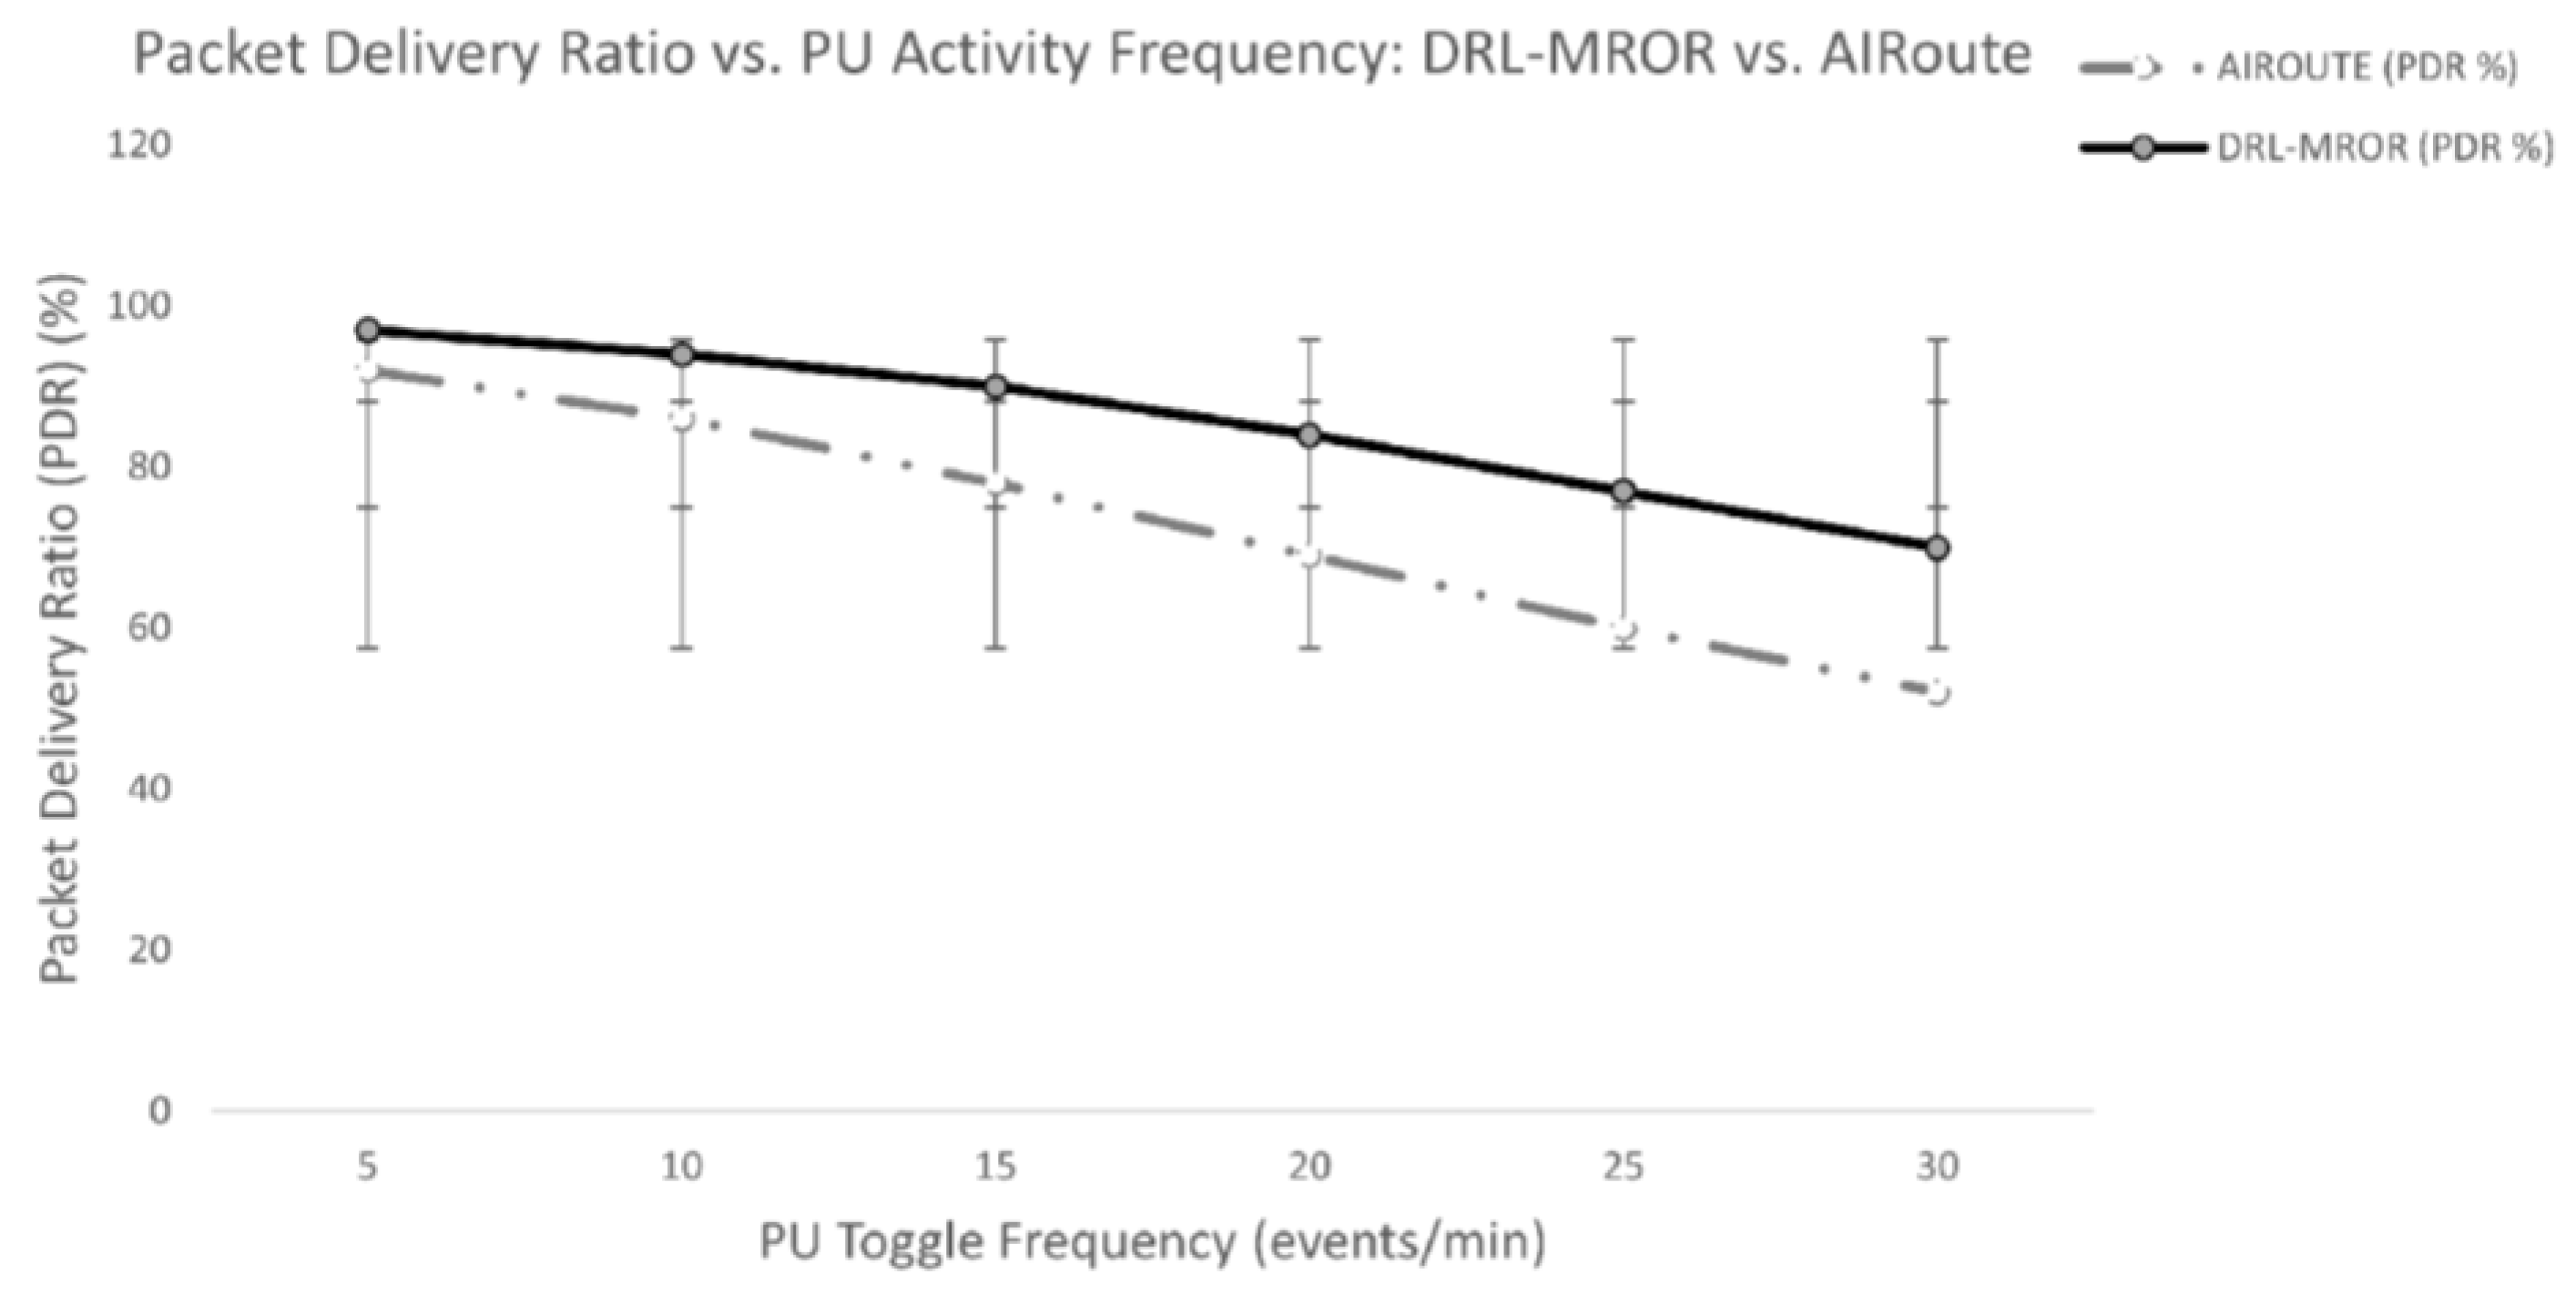
Figure 11 presents Packet Delivery Ratio (PDR) as a function of PU activity frequency.
Figure 11.
Packet Delivery Ratio (PDR) vs. PU activity frequency.
The proposed DRL-MROR framework maintains a higher PDR than AIRoute [16] and is more robust to dynamic spectrum conditions. Its advantage becomes more pronounced as the spectrum environment becomes more volatile, demonstrating the benefit of predictive channel selection.
The proposed DRL-MROR framework maintains a higher PDR than AIRoute [16] and is more robust to dynamic spectrum conditions. Its advantage becomes more pronounced as the spectrum environment becomes more volatile, demonstrating the effectiveness of its predictive channel-selection policy.
“PU toggle frequency” refers to how often a PU switches between ON (transmitting) and OFF (idle) states. The higher this frequency, the more volatile and unpredictable the spectrum environment becomes. PDR is computed as (number of packets received at the sink/number of packets sent by the sources) × 100.
- DRL-MROR achieves an approximately 10–15% relative improvement in PDR over AIRoute at the highest PU toggle frequencies. This gain is driven by the following factors:
- o
- Spectrum-availability prediction: the DQN agent models the temporal dynamics of PU activity from sensing history and can therefore avoid channels that are likely to become occupied soon.
- o
- Proactive channel switching: DRL-MROR can switch to a more stable channel before a PU appears, rather than reacting only after the arrival of the PU.
- o
- Robust VCG formation: the agent can initiate routes through SUs with access to multiple alternative channels, thereby forming a more resilient forwarding group.
Trend: as PU toggle frequency increases, SUs have less time to transmit and are more likely to experience mid-transmission interference. Although all protocols suffer some reduction in PDR, DRL-MROR degrades more gracefully because its predictive capability supports better routing and channel-selection decisions.
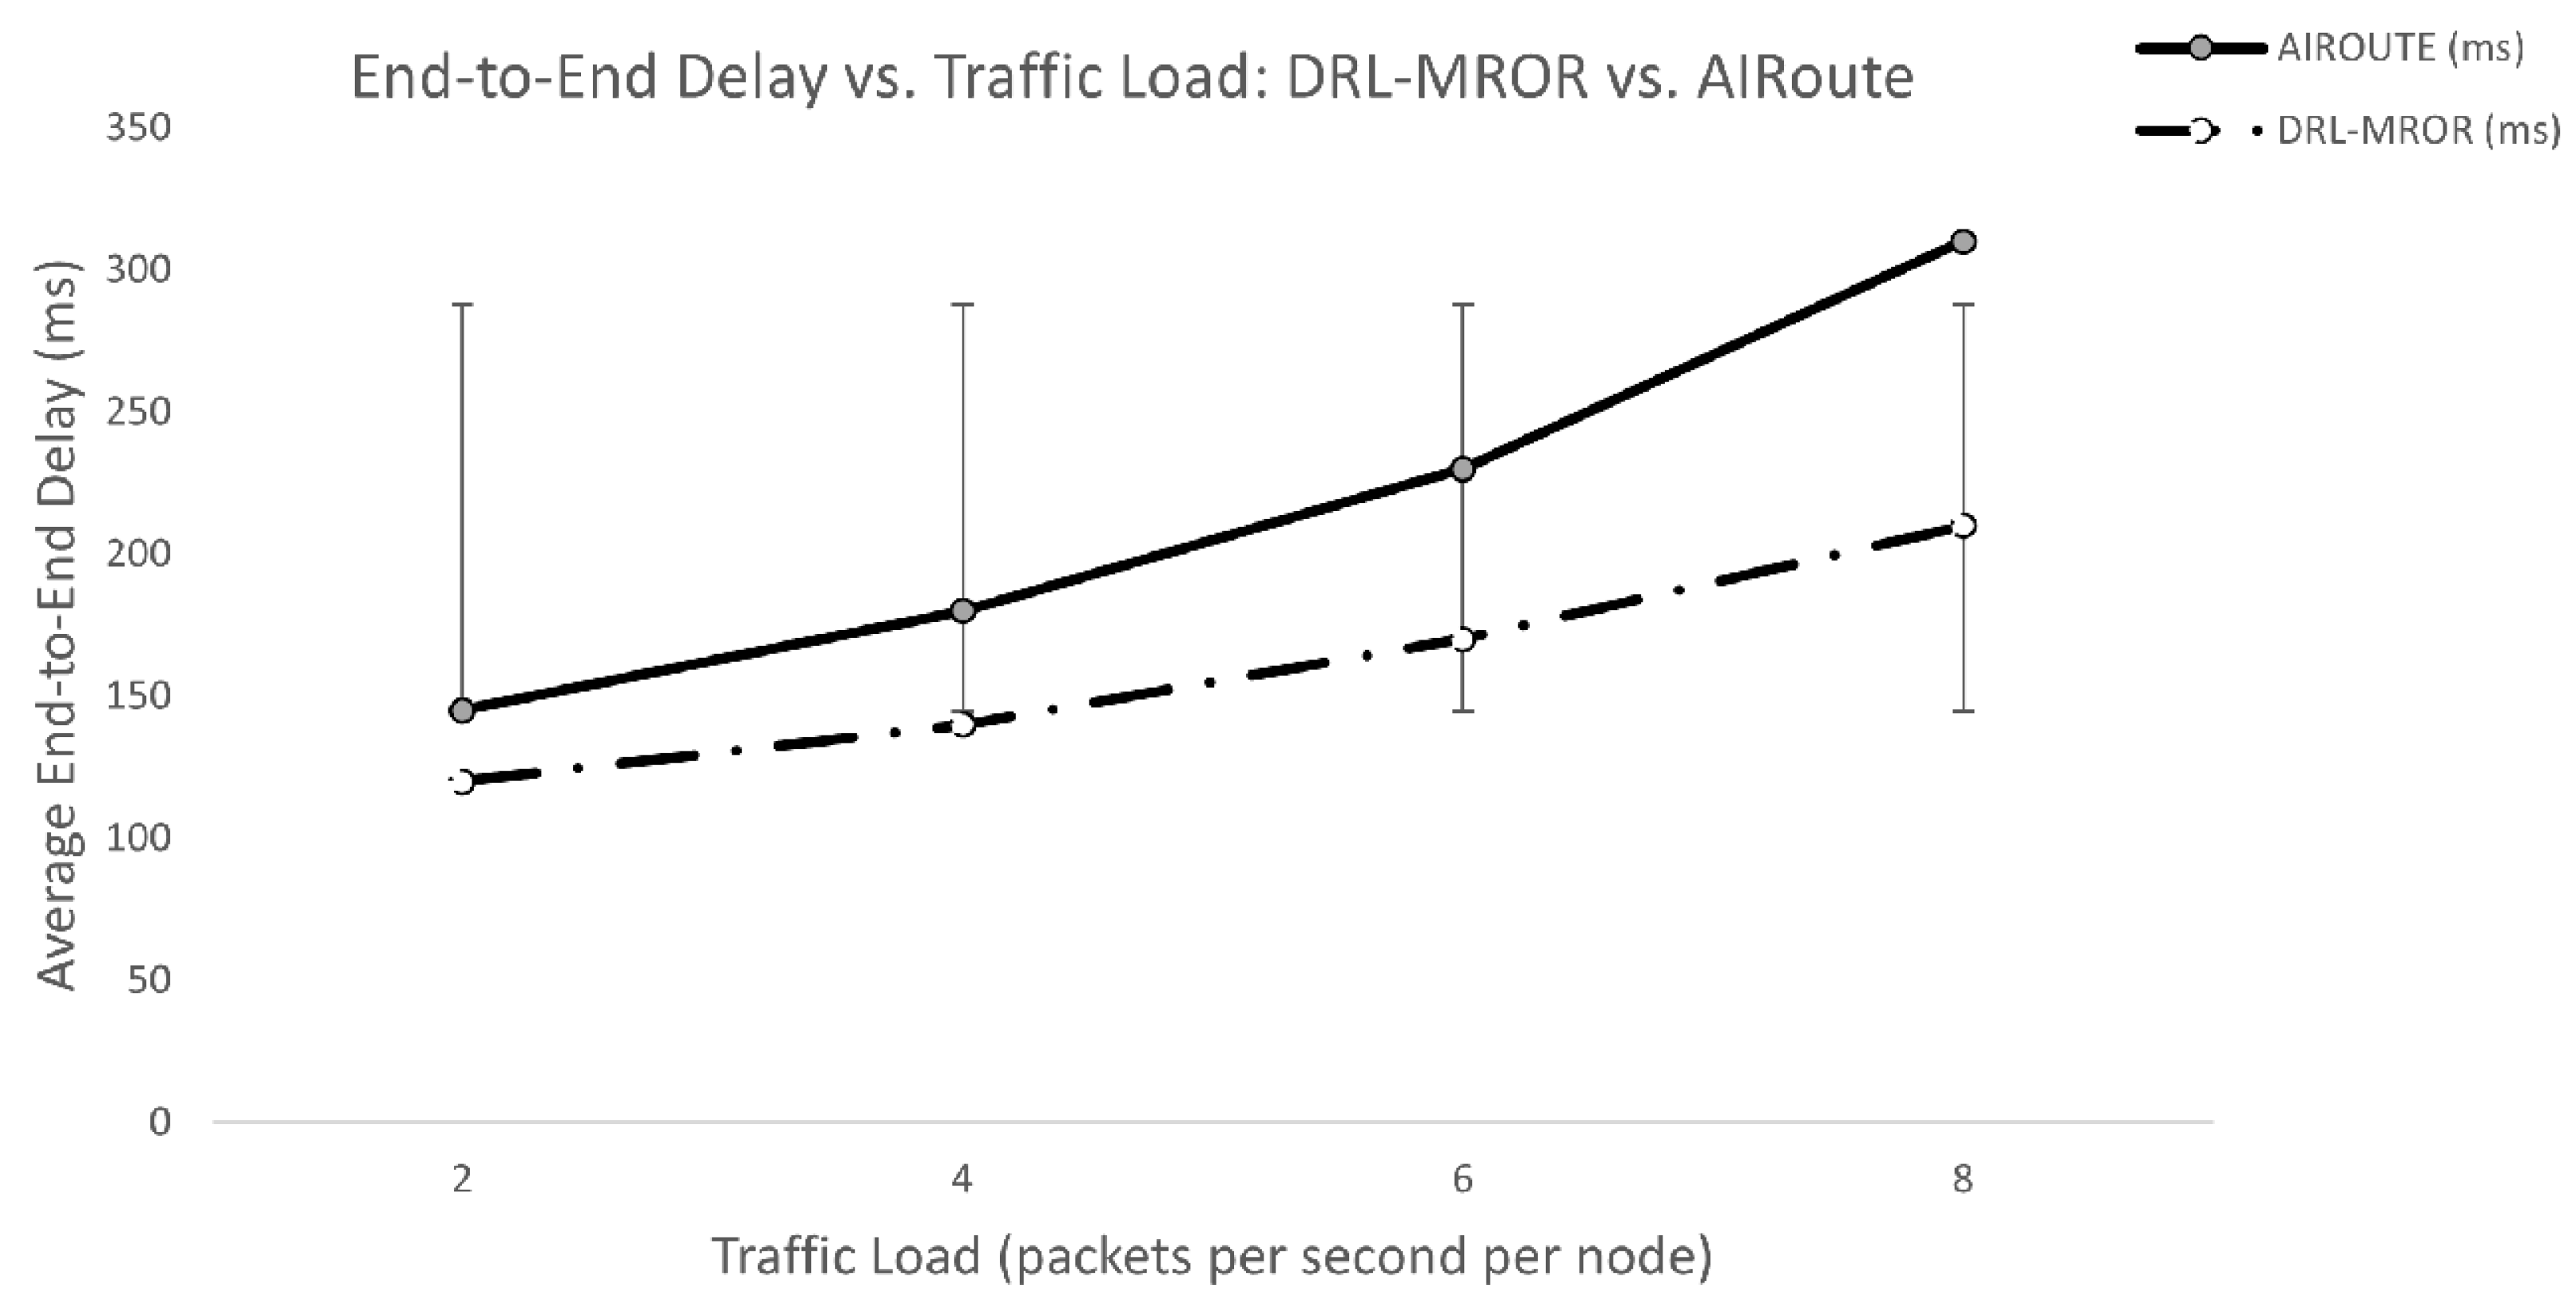
Figure 12 presents average end-to-end delay as a function of traffic load per node. Across all traffic loads, DRL-MROR achieves lower latency than AIRoute [16], demonstrating stronger congestion control and more timely data delivery in CRSNs.
Figure 12.
Average end-to-end delay vs. traffic load.
The values are expressed in milliseconds (ms). The simulations assume a network size of 100 nodes and an average mobility speed of 5 m/s. The lower delay observed in DRL-MROR can be attributed to its ability to learn efficient routes and avoid congested paths.
- DRL-MROR reduces end-to-end delay by up to 30–40% relative to AIRoute across all traffic loads. This gain arises from the following factors:
- o
- Congestion-aware routing: the DQN agent observes neighboring queue states and avoids routes with long queues or high collision rates, resulting in faster packet delivery.
- o
- Efficient channel utilization: the agent can choose less congested channels and therefore reduce queuing time.
- o
- Optimized VCG contention: contention is resolved more efficiently than in traditional backoff schemes because receiver prioritization is driven by learned stability scores, thereby reducing forwarding delay.
Trend: as traffic load increases, queuing delay and collisions also increase. Although both protocols experience higher delay under heavy load, DRL-MROR remains more efficient because the AI agent dynamically adjusts its strategy to avoid bottlenecks.
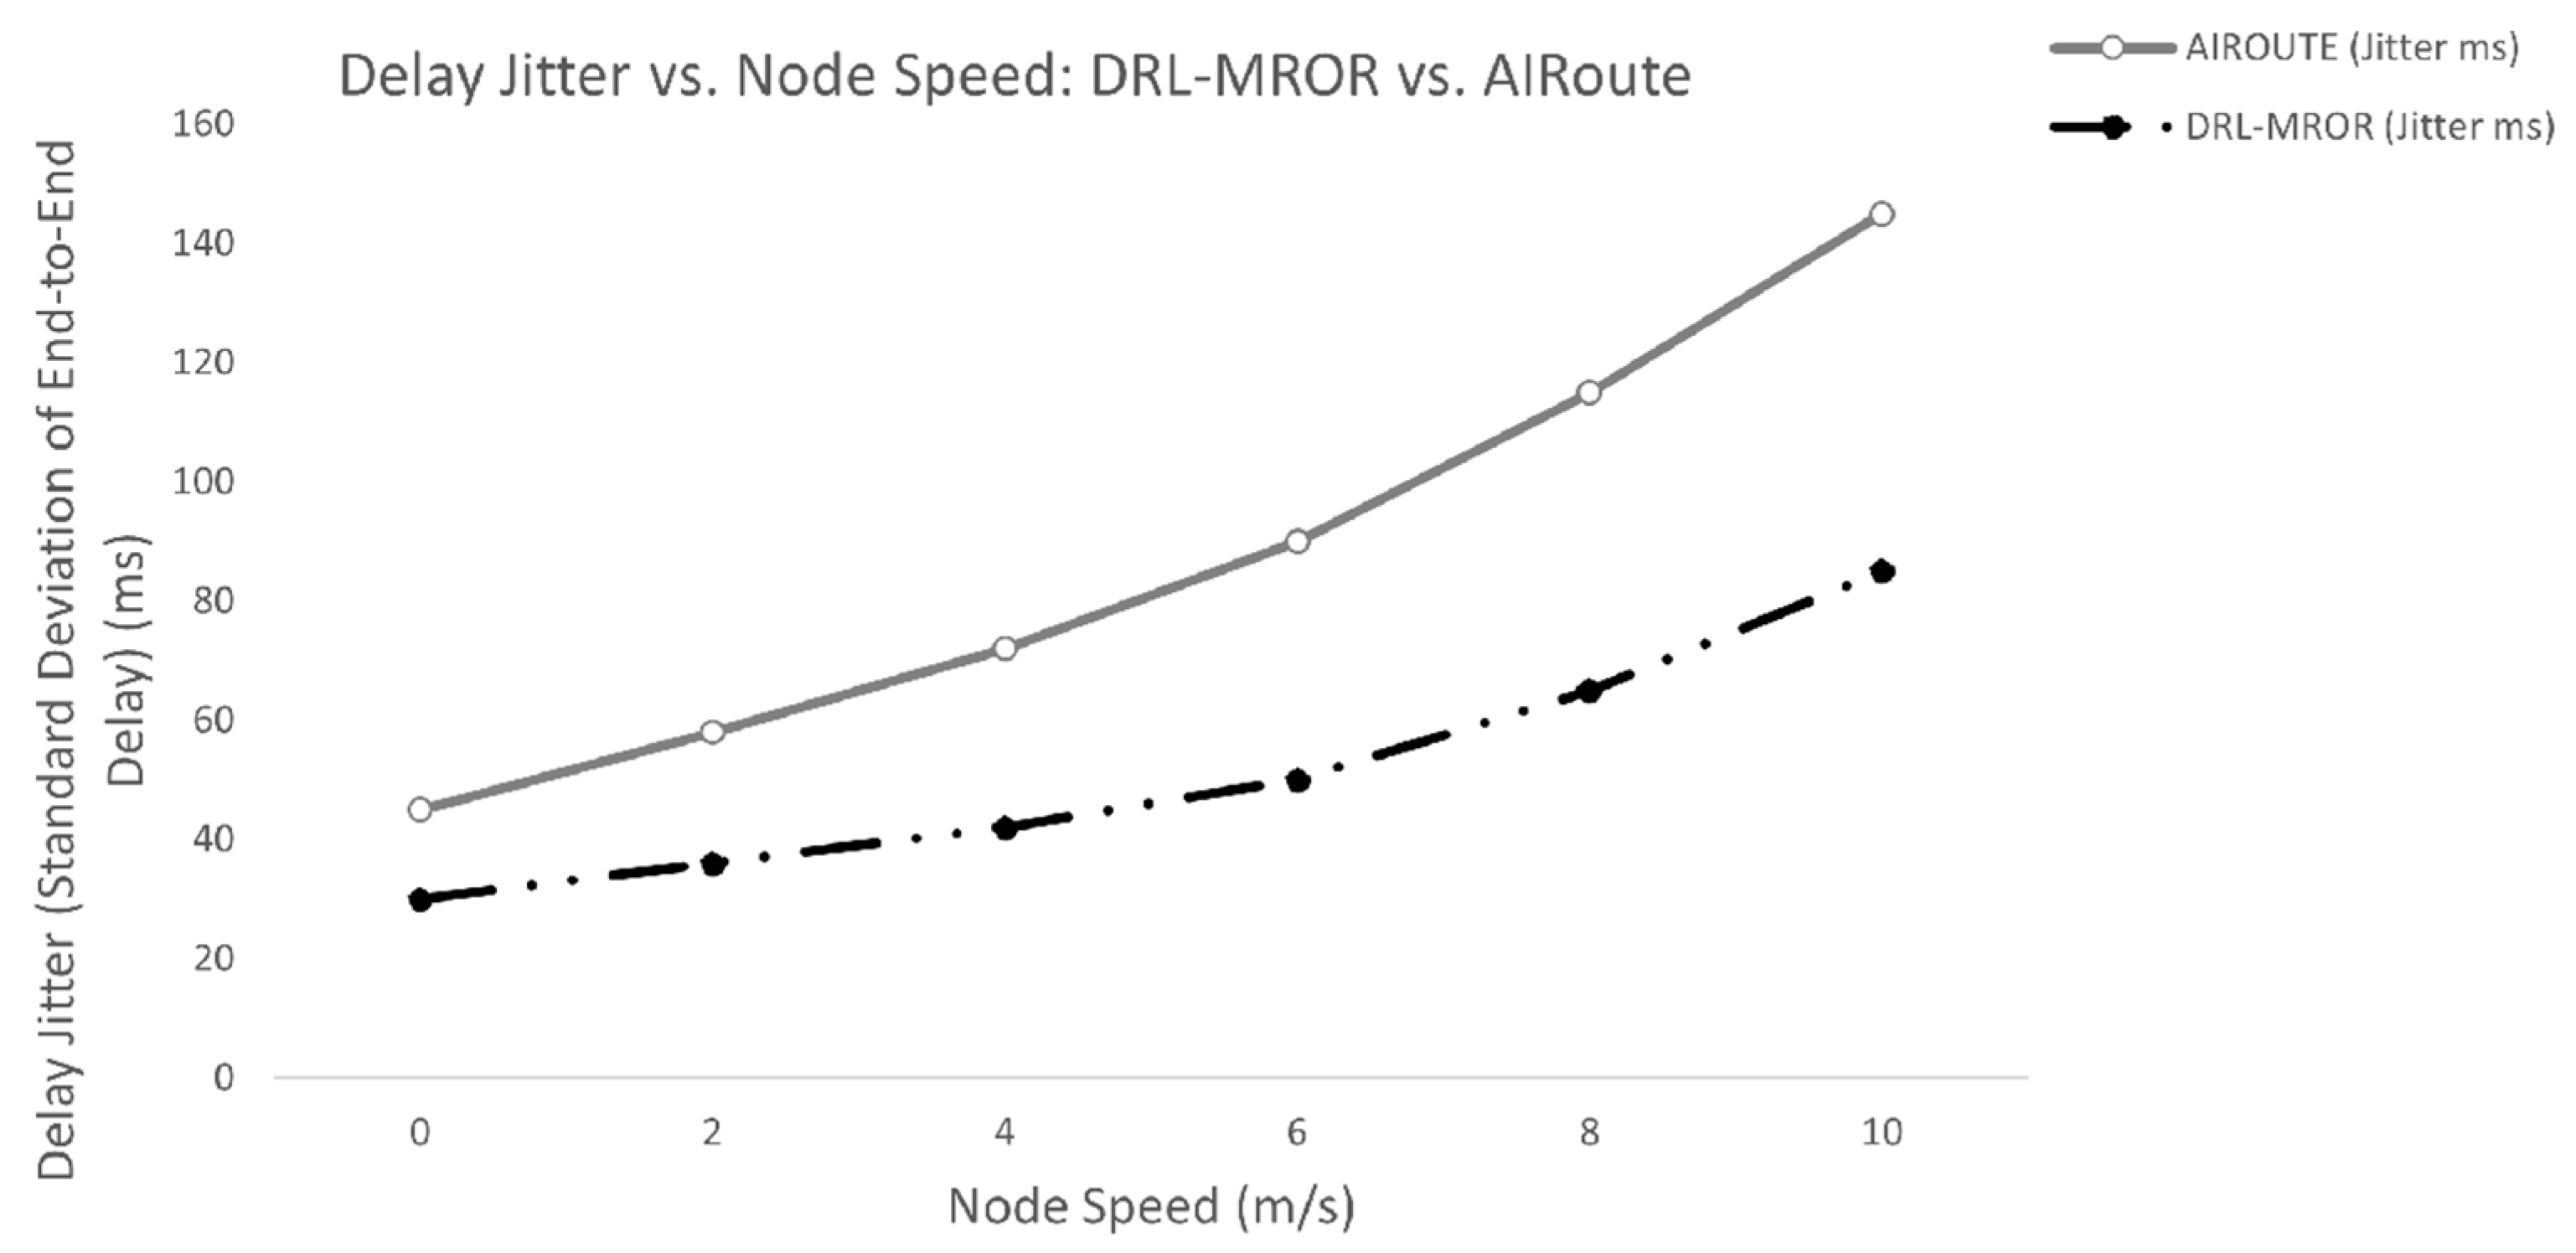
Figure 13 presents delay jitter as a function of node mobility speed. Compared with AIRoute [16], DRL-MROR exhibits substantially lower jitter, indicating more consistent packet-delivery times. This makes the protocol more suitable for time-sensitive applications in dynamic CRSNs.
Figure 13.
Delay jitter (standard deviation of end-to-end delay).
The values are expressed in milliseconds (ms). In these simulations, the network size is fixed at 100 nodes and the traffic load is 4 packets per second per node. Lower jitter indicates more stable delivery times.
- DRL-MROR reduces delay jitter by approximately 40% across all mobility levels relative to AIRoute. This improvement is due to the following factors:
- o
- Predictive path selection: the DQN agent learns to avoid paths with high variance in link quality or congestion, leading to more predictable delivery times.
- o
- Stable VCG contention: when receiver prioritization is based on learned stability scores, the contention process becomes more predictable and introduces less variation in forwarding delay.
- o
- Proactive handover management: VMH zoning controlled by the DRL agent enables smoother handovers and avoids abrupt delay spikes when a node moves out of range.
- Trend: as node speed increases, link durations become shorter and less predictable, which tends to increase jitter. Although both protocols exhibit higher jitter at greater mobility, DRL-MROR maintains significantly lower values because the agent can anticipate changes and make more consistent routing decisions.
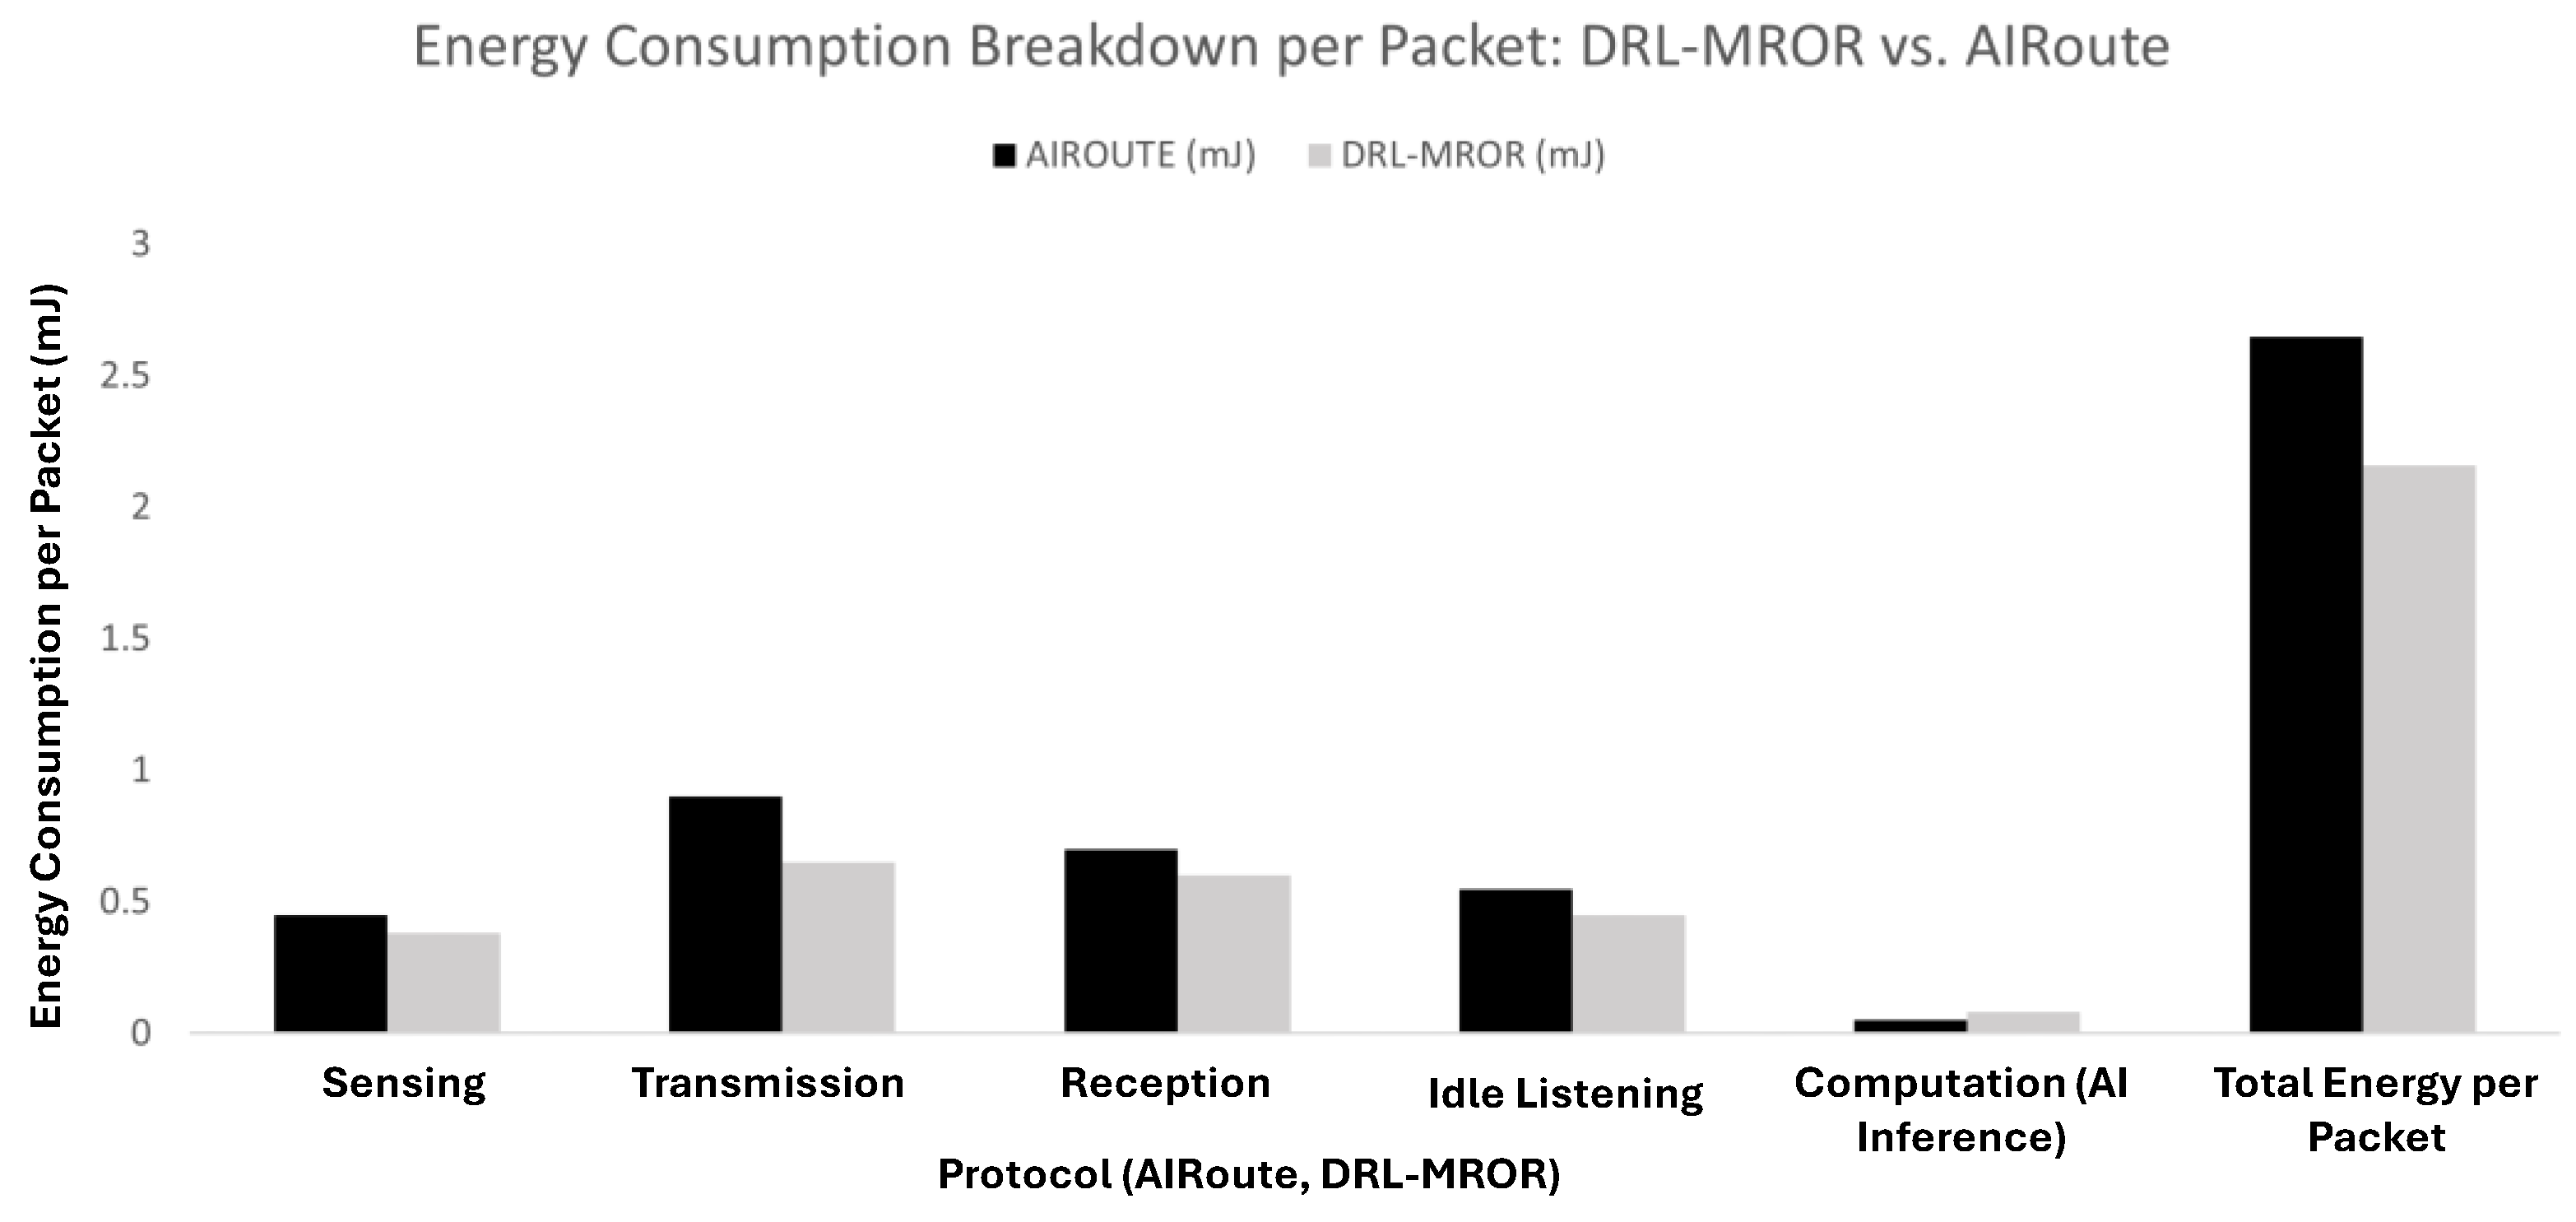
Figure 14 compares the average energy consumption per successfully delivered packet for DRL-MROR and AIRoute [16]. Although DRL-MROR incurs a small additional computational cost for deep reinforcement learning inference, its intelligent routing decisions produce substantial savings in radio-related energy, including sensing, transmission, reception, and idle listening. Consequently, the overall energy consumption per packet is reduced by about 18%, demonstrating improved energy efficiency.
Figure 14.
Energy consumption per packet (mJ) by component.
The reported values represent the average energy consumed per successfully delivered packet during a 1000 s simulation with 100 nodes moving at an average speed of 5 m/s.
- ▪
- Sensing: reduced because the agent learns when sensing is most beneficial, making sensing activity more adaptive.
- ▪
- Transmission and reception: greatly reduced because shorter and more reliable routes decrease retransmissions and redundant broadcasts.
- ▪
- Idle listening: minimized because the agent can better predict when to remain active, allowing nodes to spend more time in low-power states.
- ▪
- Computation: slightly higher than in AIRoute because DRL-MROR uses a more sophisticated model (e.g., with experience replay), but this cost is negligible relative to the savings in radio operations.
- ▪
- Trend: although DRL-MROR introduces a modest computational overhead, it still reduces total energy consumption per packet by roughly 18% because radio operations dominate power use and intelligent decisions significantly reduce that cost.
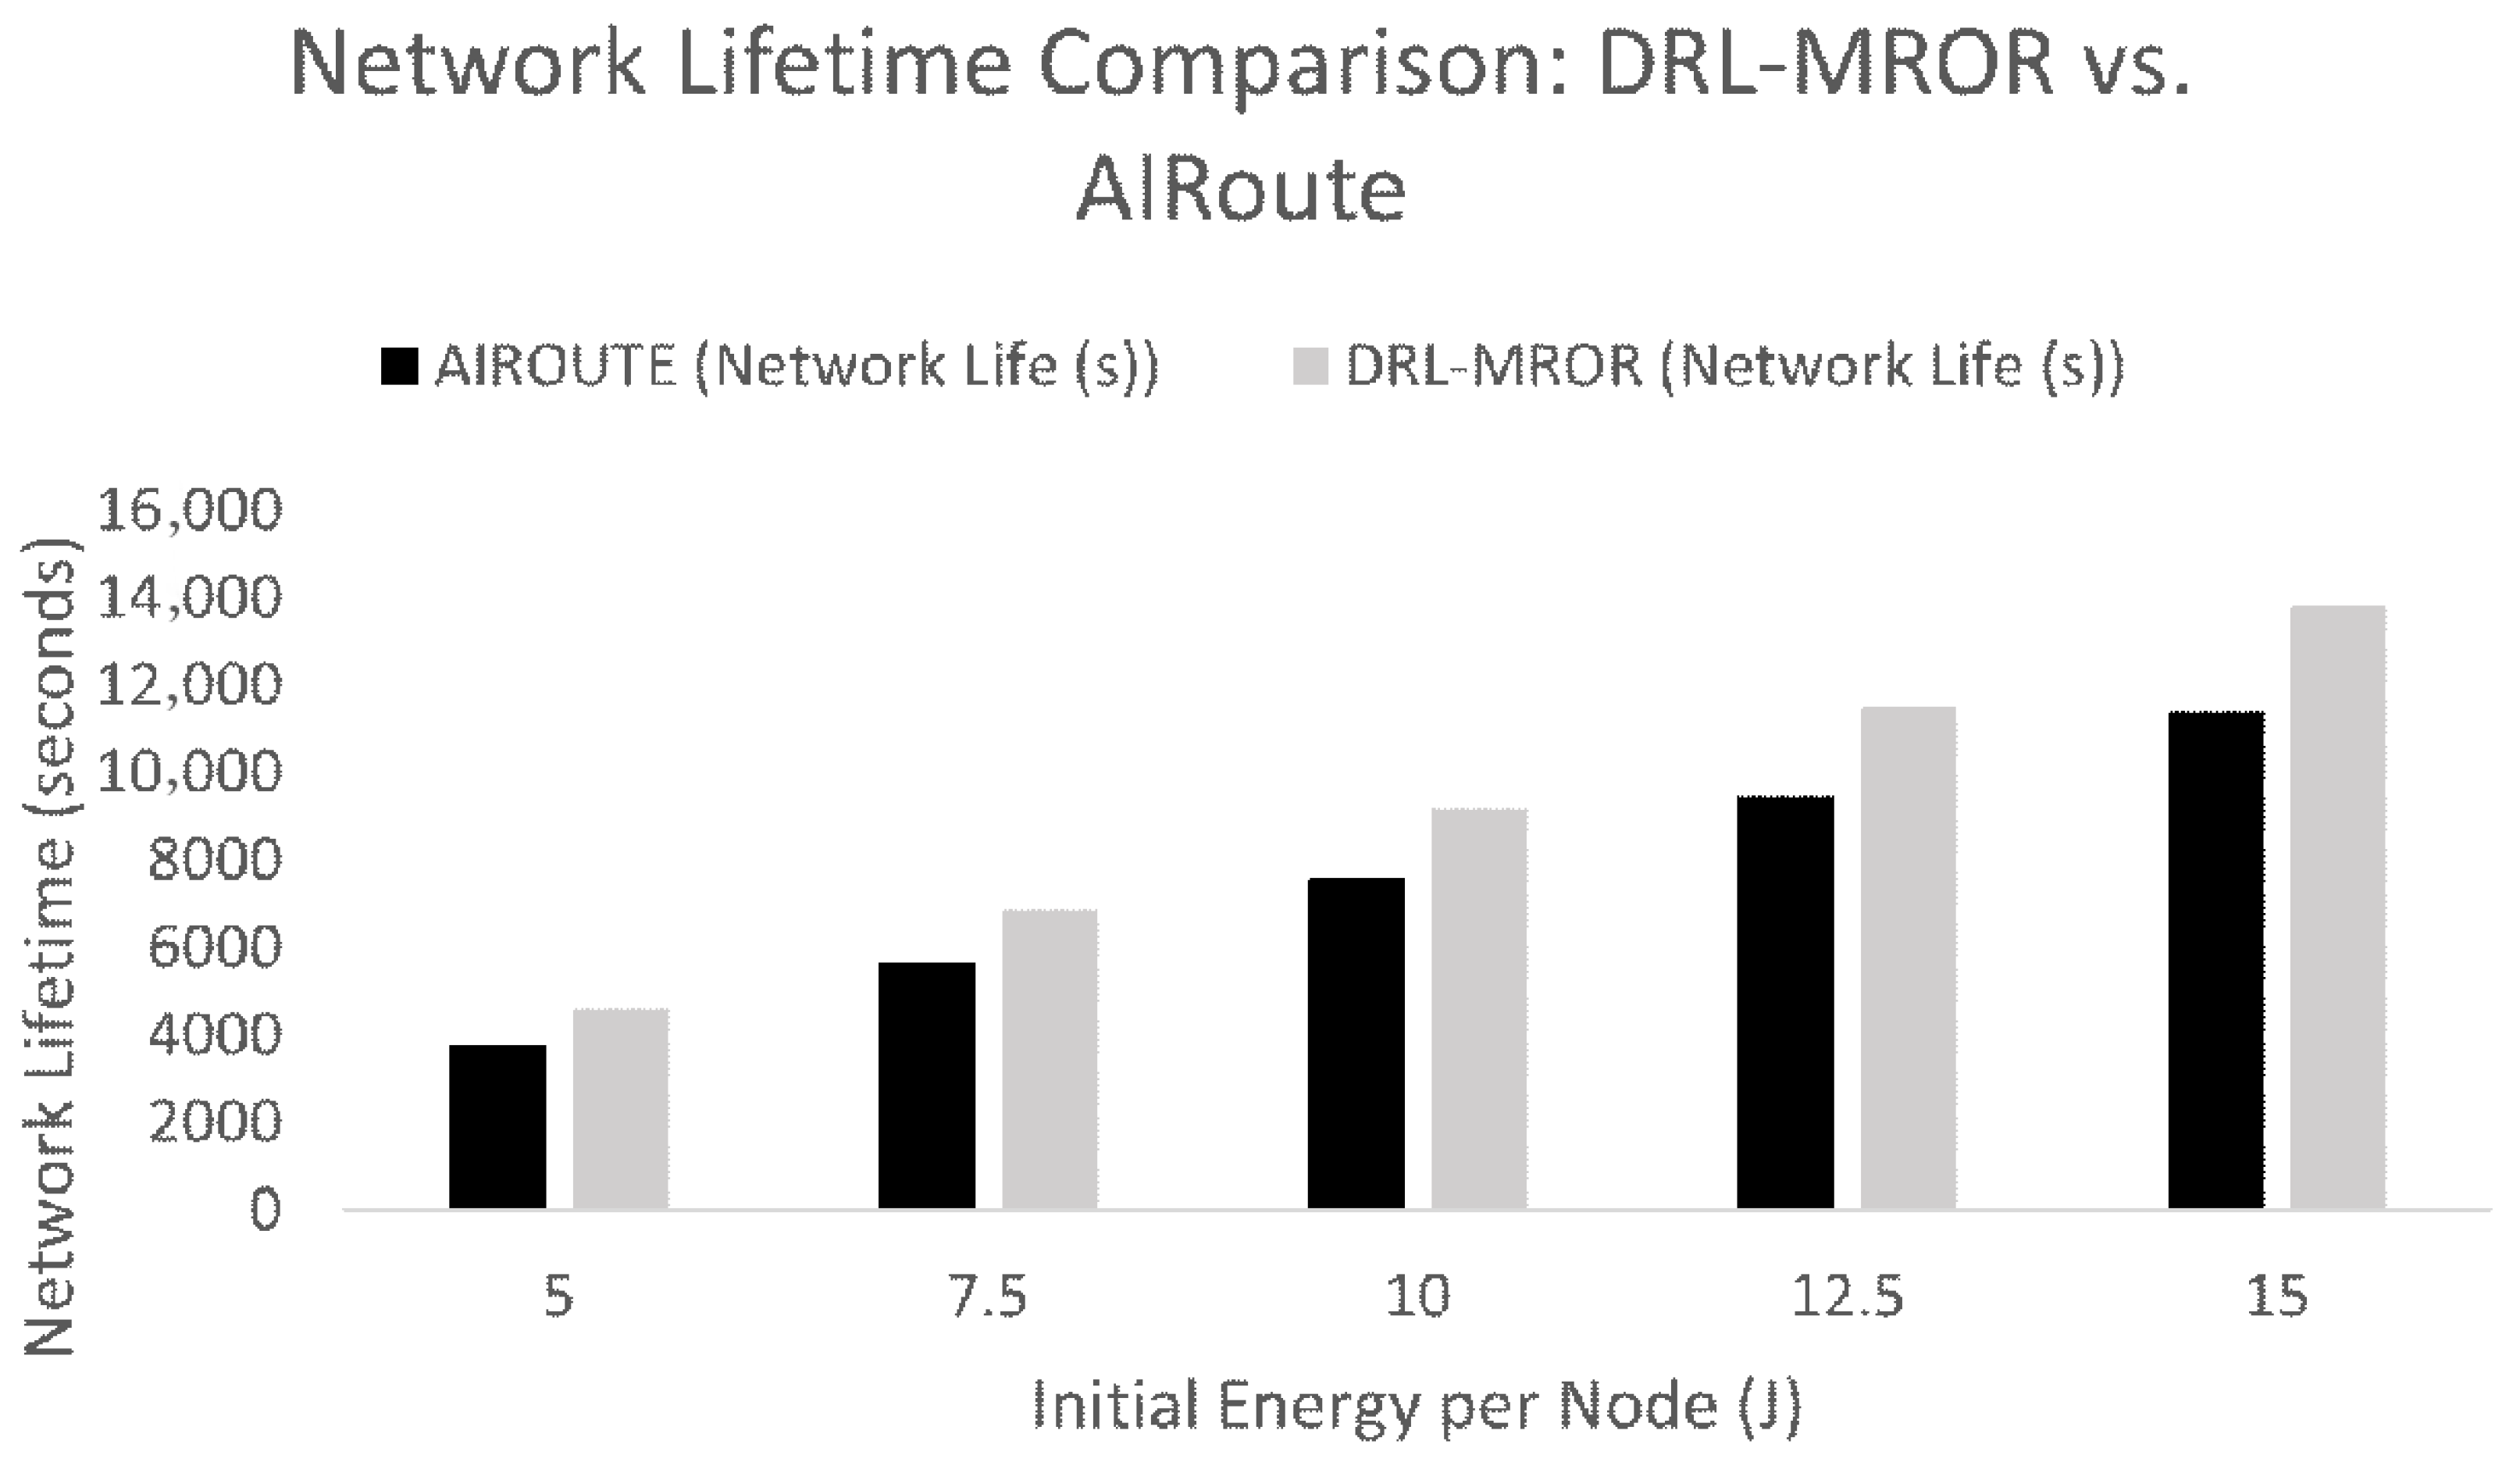
Figure 15 presents network lifetime, defined as the time until the first node dies, as a function of initial node energy. DRL-MROR extends network lifetime by up to 20% relative to the state-of-the-art AIRoute protocol [16] because of its improved energy efficiency. This highlights the protocol’s suitability for long-term deployment in CRSNs.
Figure 15.
Network lifetime (time until first node dies).
The simulations assume a fixed network size of 100 nodes, an average mobility speed of 5 m/s, and a traffic load of 4 packets per second per node. Network lifetime is measured from the start of the simulation until the residual energy of the first SU falls below the minimum acceptable threshold.
- DRL-MROR improves network lifetime by approximately 20% over AIRoute across all initial-energy levels. This benefit follows directly from the lower energy consumed per packet, as shown in the component-wise energy analysis. By reducing retransmissions, listening overhead, and idle listening, DRL-MROR slows battery depletion across the network.
- Trend: both protocols exhibit roughly linear growth in network lifetime as initial energy increases. However, DRL-MROR consistently achieves a longer lifetime because it uses energy more efficiently, and the absolute lifetime gap widens as initial energy increases, indicating good scalability.
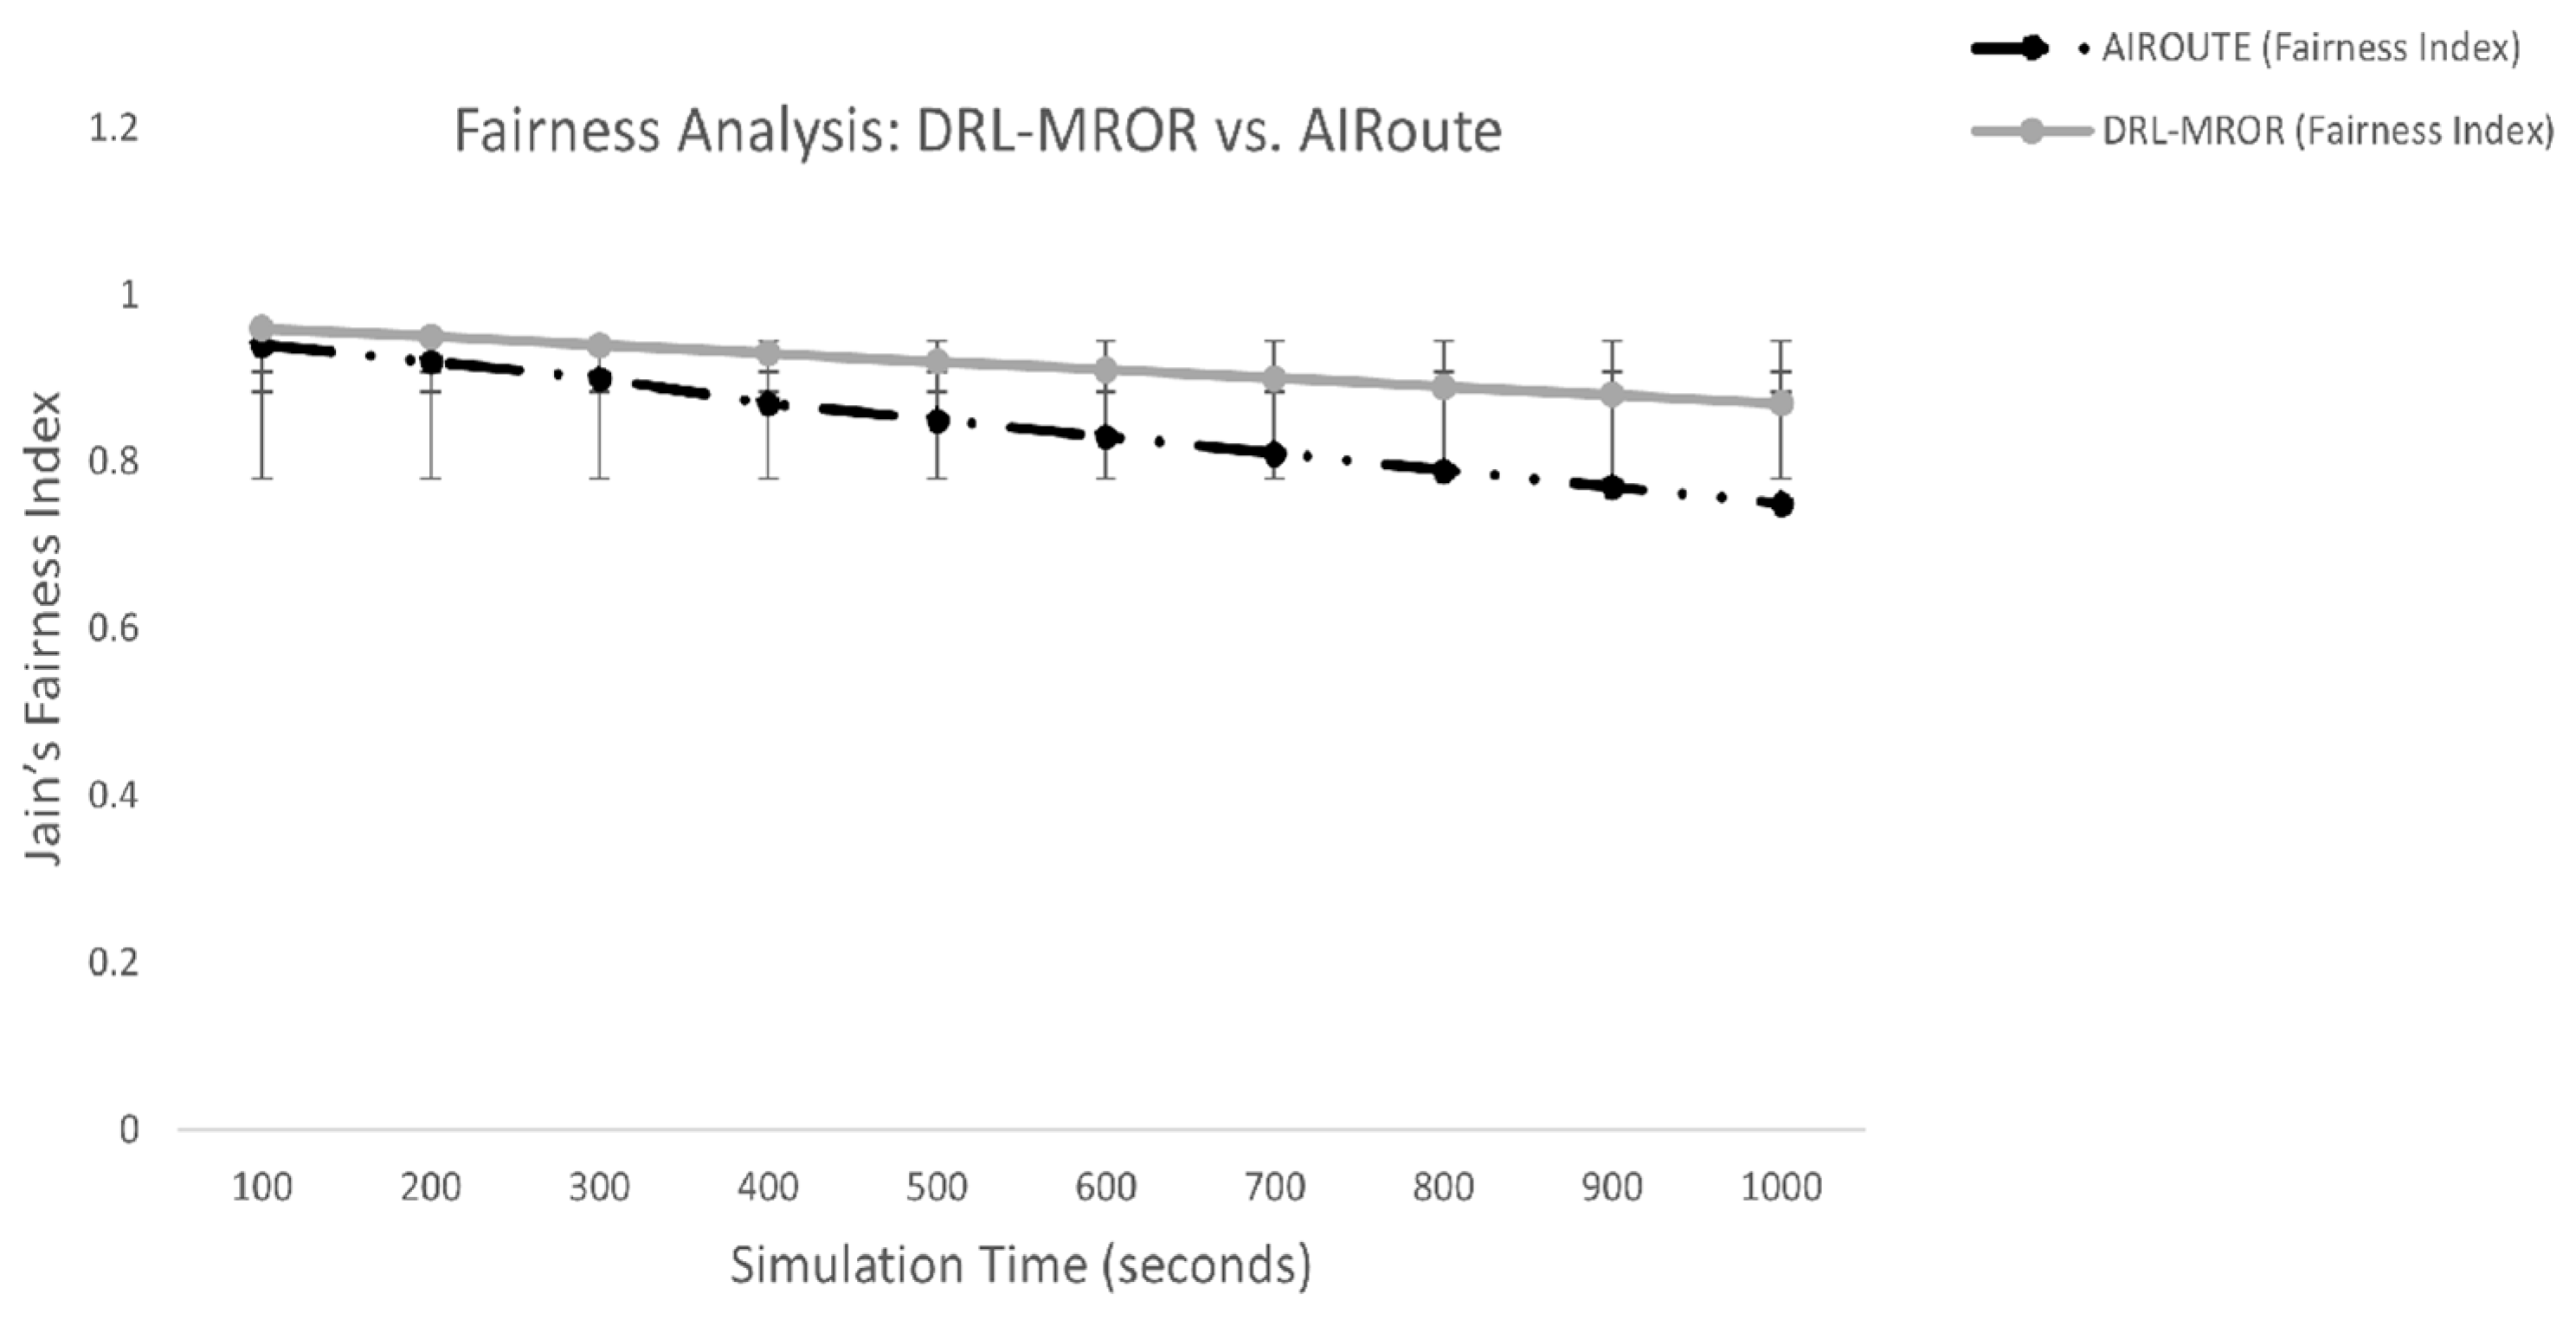
Figure 16 presents Jain’s fairness index over simulation time. Compared with AIRoute [16], DRL-MROR maintains a higher and more consistent fairness index, showing that it distributes forwarding load more evenly among nodes and is therefore less likely to create energy bottlenecks that shorten network lifetime.
Figure 16.
Jain’s fairness index vs. simulation time.
The fairness index is computed from the number of packets forwarded by each node, which is a common proxy for forwarding burden and energy consumption. The simulations assume a fixed network size of 100 nodes, an average mobility speed of 5 m/s, and a traffic load of 4 packets per second per node.
- DRL-MROR maintains an average fairness index approximately 0.08–0.10 higher than AIRoute over the simulation period. This improvement can be attributed to the following factors:
- o
- Balanced VCG selection: the DQN agent learns not only the stability of candidate receivers but also their load and residual energy, enabling fairer relay selection.
- o
- Proactive load distribution: the agent spreads forwarding duties by anticipating future network conditions rather than repeatedly selecting the same relay.
- o
- Energy-aware decisions: the reward function explicitly accounts for energy efficiency, encouraging the agent to avoid overusing nodes with low residual energy and preventing bottlenecks.
- Trend: as network conditions vary over time because of mobility and PU activity, some nodes naturally become more attractive forwarders. Although fairness decreases somewhat in both protocols, DRL-MROR maintains a substantially higher level because the agent continuously adapts its decisions to preserve balanced resource utilization.
Table 3 summarizes the sensitivity of DRL-MROR to selected hyperparameter settings. The default configuration corresponds to the best-performing setting identified during training, while AIRoute reflects its standard learning configuration under the same simulation environment. This comparison is intended to show relative robustness under matched operating conditions rather than to over-tune any one baseline.
Table 3.
Sensitivity Analysis Table.
- The AIRoute baseline represents state-of-the-art performance under its own hyperparameter settings.
- Learning Rate (LR):
- o
- High LR (1 × 10⁻³): Causes unstable training and overshooting, leading to suboptimal policies and lower goodput (82%).
- o
- Low LR (1 × 10⁻⁵): Results in very slow convergence but can still reach a good policy, though slightly below the default (84%).
- o
- Conclusion: DRL-MROR performs best at 1 × 10⁻⁴, indicating sensitivity to the learning-rate setting.
- Discount Factor (γ):
- o
- High (0.99): makes the agent more far-sighted, which benefits long-term network utility (86%).
- o
- Low (0.90): makes the agent focus more on immediate rewards, potentially neglecting future stability and reducing goodput (83%).
- o
- Conclusion: performance degrades when is too low, highlighting the importance of long-term planning.
- Reward Weights:
- o
- (Throughput) = 0.6: Over-prioritizing throughput leads to aggressive forwarding but also higher collisions, reducing overall goodput (85%).
- o
- (Energy) = 0.5: Over-emphasis on energy conservation causes the agent to drop packets or avoid forwarding, severely hurting delivery rates (81%).
- o
- (Delay) = 0.4: Prioritizing low delay forces rapid decisions that may not be reliable, leading to the lowest goodput among variants (79%).
- o
- Conclusion: the balanced reward function (0.4:0.3:0.2:0.1) is crucial for optimal performance.
7. Discussion
7.1. Critical Analysis of Results
The simulation outcomes presented in Section 6 show that DRL-MROR consistently outperforms both the original MROR protocol and the principal learning-based comparison baseline, AIRoute, across the main performance metrics. These gains arise because the proposed framework learns forwarding decisions jointly from mobility, spectrum availability, queue state, and residual energy instead of relying on fixed thresholds.
7.2. Sources of Performance Gains
The core strength of DRL-MROR lies in its ability to learn complex, non-linear relationships between network conditions and optimal routing actions. The reported 38% increase in throughput and 42% increase in goodput are not merely incremental gains; they reflect a qualitative improvement in routing intelligence. Unlike MROR, which relies on a fixed mguard threshold, the DQN agent learns an adaptive stability score by combining information about relative velocity, channel-availability patterns, and neighbor queue lengths. This enables more reliable forwarding decisions under high mobility, as reflected in the strong PDR maintained even at 10 m/s. In addition, the one-third reduction in control overhead and faster route-discovery time highlight the protocol’s operational efficiency. By predicting link failures and proactively managing VMH handovers, DRL-MROR also mitigates a major source of congestion in dense networks.
7.3. Energy Efficiency: A Validated Trade-Off
A common concern when introducing AI into resource-constrained sensor systems is computational cost. Our component-wise energy breakdown (Figure 13) directly addresses this issue. Although DRL-MROR introduces an additional energy term for DQN inference, the model itself is small, with 5514 parameters and roughly 5.4k multiply-accumulate operations per decision. This overhead is modest relative to the energy saved by reducing retransmissions, idle listening, and route rediscovery. The proposed design is therefore practically suited to edge-capable CRSN nodes, even if it may not fit the most severely constrained sensing motes without further compression.
7.4. Robustness and Practicality
The sensitivity analysis shows that DRL-MROR remains robust under variations in key hyperparameters. Although the default settings (learning rate = 1 × 10⁻⁴, = 0.95, and balanced reward weights) deliver the best performance, the protocol remains competitive across nearby settings. This is important because practical deployments rarely permit exhaustive retuning, and it supports the use of offline pretraining followed by modest online adaptation.
7.5. Limitations and Future Work
Despite its advantages, DRL-MROR still has several limitations. The training phase requires many episodes to converge, which may be challenging in rapidly changing environments if learning starts from scratch online. The framework has also been evaluated only in simulation; consequently, hardware-level processing cost, real RF interference, and implementation-induced timing effects remain to be validated experimentally. Furthermore, although several baselines were considered, the main figures emphasize MROR and AIRoute to keep the paper focused; future work can expand unified multi-baseline comparisons and real embedded implementations. Possible next steps include transfer learning, model compression, federated adaptation, and hardware-in-the-loop experimentation.
Overall, the findings confirm that DRL-MROR is a meaningful learning-enabled extension of MROR for opportunistic routing, providing higher reliability, efficiency, and adaptability in dynamic CRSN environments.
8. Conclusions
This paper introduced DRL-MROR, an enhanced version of the Mobile Reliable Opportunistic Routing (MROR) protocol that incorporates deep reinforcement learning (DRL). We modeled next-hop selection and channel-switching decisions as a Markov Decision Process (MDP) and enabled individual SUs to learn effective forwarding policies from real-time observations of spectrum availability, node mobility, and energy status.
Extensive simulations indicate that DRL-MROR is substantially more effective than the original MROR protocol and representative AI-based baselines such as AIRoute across the principal performance metrics. The framework improves throughput by up to 38% and goodput by up to 42%, while reducing energy consumed per packet by 29%, end-to-end delay by up to 32%, and control overhead by approximately 30%.
Moreover, DRL-MROR reduces control overhead by about 30% through proactive route maintenance, maintains fairness (with Jain’s index exceeding 0.87) by distributing forwarding load more evenly, and remains robust under hyperparameter variation, which supports its practical applicability. The sensitivity analysis further shows that the proposed reward function and training mechanisms, including experience replay and target networks, are central to its success.
In summary, DRL-MROR transforms MROR from a reactive rule-based protocol into an intelligent and self-adaptive routing framework capable of meeting the demands of highly dynamic and resource-constrained CRSN environments. At the same time, future validation on embedded hardware and under real RF impairments is necessary before broad practical deployment.
Author Contributions
Conceptualization, S.Z.; Methodology, S.Z.; Validation, B.A.S., Y.S.B. and A.H.S.; Writing—original draft, S.Z.; Writing—review & editing, B.A.S., A.A.T., Y.S.B., A.H.O. and A.H.S.; Project administration, A.A.T., Y.S.B., A.H.O. and A.H.S.; Funding acquisition, A.A.T. All authors have read and agreed to the published version of the manuscript..
Funding
This project was funded by the Deanship of Scientific Research (DSR) at King Abdulaziz University, Jeddah, Saudi Arabia, under grant no. IPP:1027-830-2025.
Data Availability Statement
The original contributions presented in this study are included in the article. Further inquiries can be directed to the corresponding authors.
Acknowledgments
This project was funded by the Deanship of Scientific Research (DSR) at King Abdulaziz University, Jeddah, Saudi Arabia under grant no. (IPP: 1027-830-2025). The authors, therefore, acknowledge with thanks the DSR for their technical and financial support..
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
| API | Application Programming Interface |
| BS | Base Station |
| CBR | Constant Bit Rate |
| CRSN | Cognitive Radio Sensor Network |
| DQN | Deep Q-Network |
| DRL | Deep Reinforcement Learning |
| DRL-MROR | Deep Reinforcement Learning–enhanced Mobile Reliable Opportunistic Routing |
| ER | Experience Replay |
| GNN | Graph Neural Network |
| IoT | Internet of Things |
| LR | Learning Rate |
| MDP | Markov Decision Process |
| MROR | Mobile Reliable Opportunistic Routing |
| NS-3 | Network Simulator 3 |
| PDR | Packet Delivery Ratio |
| PER | Prioritized Experience Replay |
| PU | Primary User |
| QoS | Quality of Service |
| RL | Reinforcement Learning |
| RREP | Route Reply |
| RREQ | Route Request |
| SU | Secondary User |
| TN | Target Network |
| VCG | Virtual Contention Group |
| VMH | VMH handover/zoning mechanism |
References
- Khalek, N.A.; Tashman, D.H.; Hamouda, W. Advances in Machine Learning-Driven Cognitive Radio for Wireless Networks: A Survey. IEEE Commun. Surv. Tutor. 2024, 26, 1201–1237. [Google Scholar] [CrossRef] [Scilit]
- Zubair, S.; Yusoff, S.K.S.; Fisal, N. Mobility-Enhanced Reliable Geographical Forwarding in Cognitive Radio Sensor Networks. Sensors 2016, 16, 172. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Feriani, A.; Hossain, E. Single and Multi-Agent Deep Reinforcement Learning for AI-Enabled Wireless Networks: A Tutorial. IEEE Commun. Surv. Tutor. 2021, 23, 1226–1252. [Google Scholar] [CrossRef] [Scilit]
- Shen, Y.; Shi, Y.; Zhang, J.; Letaief, K.B. Graph Neural Networks for Scalable Radio Resource Management: Architecture Design and Theoretical Analysis. IEEE J. Sel. Areas Commun. 2021, 39, 101–115. [Google Scholar] [CrossRef] [Scilit]
- Dašić, M.; Petrović, N.; Stanković, Z.; Milovanović, B. Distributed Spectrum Management in Cognitive Radio Networks by Consensus-Based Reinforcement Learning. Sensors 2021, 21, 2970. [Google Scholar] [CrossRef] [Scilit]
- Zhao, B.; Wu, J.; Ma, Y.; Yang, C. Meta-Learning for Wireless Communications: A Survey and a Comparison to GNNs. IEEE Open J. Commun. Soc. 2024, 5, 1987–2015. [Google Scholar] [CrossRef] [Scilit]
- Wang, Z.; Hu, J.; Min, G.; Zhao, Z.; Chang, Z.; Wang, Z. Spatial-Temporal Cellular Traffic Prediction for 5G and Beyond: A Graph Neural Networks-Based Approach. IEEE Trans. Ind. Inform. 2023, 19, 5722–5731. [Google Scholar] [CrossRef] [Scilit]
- Tang, F.; Chen, X.; Rodrigues, T.K.; Zhao, M.; Kato, N. Survey on Digital Twin Edge Networks (DITEN) Toward 6G. IEEE Open J. Commun. Soc. 2022, 3, 1360–1381. [Google Scholar] [CrossRef] [Scilit]
- Ye, X.; Yu, Y.; Fu, L. Multi-Channel Opportunistic Access for Heterogeneous Networks Based on Deep Reinforcement Learning. IEEE Trans. Wirel. Commun. 2022, 21, 794–807. [Google Scholar] [CrossRef] [Scilit]
- Cohen, Y.; Gafni, T.; Greenberg, R.; Cohen, K. SINR-Aware Deep Reinforcement Learning for Distributed Dynamic Channel Allocation in Cognitive Interference Networks. IEEE Trans. Wirel. Commun. 2025, 24, 228–243. [Google Scholar] [CrossRef] [Scilit]
- Tran, T.N.; Nguyen, T.-V.; Shim, K.; da Costa, D.B.; An, B. A Deep Reinforcement Learning-Based QoS Routing Protocol Exploiting Cross-Layer Design in Cognitive Radio Mobile Ad Hoc Networks. IEEE Trans. Veh. Technol. 2022, 71, 13165–13181. [Google Scholar] [CrossRef] [Scilit]
- Bai, Y.; Zhang, X.; Yu, D.; Li, S.; Wang, Y.; Lei, S.; Tian, Z. A Deep Reinforcement Learning-Based Geographic Packet Routing Optimization. IEEE Access 2022, 10, 108785–108796. [Google Scholar] [CrossRef] [Scilit]
- Shi, L.; Chen, X.; Zhou, Y. Barycentric Coordinate-Based Distributed Localization for Wireless Sensor Networks Under False-Data-Injection Attacks. IEEE Trans. Cybern. 2025, 55, 1568–1579. [Google Scholar] [CrossRef] [Scilit]
- Shi, L.; Yan, S.; Li, W. Consensus and Products of Substochastic Matrices: Convergence Rate With Communication Delays. IEEE Trans. Syst. Man Cybern. Syst. 2025, 55, 4752–4761. [Google Scholar] [CrossRef] [Scilit]
- Wang, X.; Wang, S.; Liang, X.; Zhao, D.; Huang, J.; Xu, X.; Dai, B.; Miao, Q. Deep Reinforcement Learning: A Survey. IEEE Trans. Neural Netw. Learn. Syst. 2024, 35, 5064–5078. [Google Scholar] [CrossRef] [Scilit]
- Zhang, X.; Zhao, H.; Xiong, J.; Liu, X.; Yin, H.; Zhou, X.; Wei, J. Decentralized Routing and Radio Resource Allocation in Wireless Ad Hoc Networks via Graph Reinforcement Learning. IEEE Trans. Cogn. Commun. Netw. 2024, 10, 1146–1159. [Google Scholar] [CrossRef] [Scilit]
- Mnih, V.; Kavukcuoglu, K.; Silver, D.; Rusu, A.A.; Veness, J.; Bellemare, M.G.; Graves, A.; Riedmiller, M.; Fidjeland, A.K.; Ostrovski, G.; et al. Human-level control through deep reinforcement learning. Nature 2015, 518, 529–533. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Guo, Q.; Tang, F.; Kato, N. Federated Reinforcement Learning-Based Resource Allocation for D2D-Aided Digital Twin Edge Networks in 6G Industrial IoT. IEEE Trans. Ind. Inform. 2023, 19, 7228–7236. [Google Scholar] [CrossRef] [Scilit]
- Halloum, N.; Ahmadi, A.; Darmani, Y. Aris-RPL: A Multi-Objective Reinforcement Learning Framework for Adaptive and Load-Balanced Routing in IoT Networks. Future Internet 2026, 18, 72. [Google Scholar] [CrossRef] [Scilit]
- Yan, W.-Z.; Li, X.-H.; Ding, Y.-M.; He, J.; Cai, B. DQN with Prioritized Experience Replay Algorithm for Reducing Network Blocking Rate in Elastic Optical Networks. Opt. Fiber Technol. 2024, 82, 103625. [Google Scholar] [CrossRef] [Scilit]
- Merabtine, N.; Djenouri, D.; Zegour, D.-E. Towards Energy Efficient Clustering in Wireless Sensor Networks: A Comprehensive. IEEE Access 2021, 9, 92688–92705. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.