


Abstract
In intelligence research, the sharing of item response data from cognitive ability assessments is often restricted by privacy concerns, while traditional parametric simulation methods frequently fail to capture complex response dependencies. This study proposes a neural network copula (NNC) framework for generating synthetic dichotomous item response data that preserves essential psychometric properties without revealing sensitive examinee information. By decoupling the modeling of marginal item probabilities from the dependence structure using a deep autoencoder and kernel density estimation, the framework accommodates the discrete nature of binary item response data while minimizing distributional assumptions. Validation against large-scale empirical data demonstrated high correspondence across multiple facets. At the data consistency level, the NNC-based synthetic data reproduced total score distributions and inter-item correlations. Psychometrically, the method yielded consistent item characteristic curve parameter estimates, item fit statistics, and test information functions. Furthermore, Monte Carlo replications demonstrated algorithmic stability and inferential precision.
1. Introduction
Synthetic data have been adopted in quantitative disciplines as a mechanism for privacy protection, reproducible research, and methodological benchmarking (Drechsler, 2011; Reiter, 2005). The core principle underlying synthetic data generation is to replace observed records with simulated observations drawn from models estimated on the original data, thereby breaking the direct linkage to real individuals while preserving inferential utility, the degree to which statistical inferences drawn from synthetic data replicate those obtainable from the original (Raab et al., 2016; Raghunathan et al., 2003; Rubin, 1993). Traditional approaches to generating synthetic item response data have relied primarily on parametric item response theory (IRT) simulation, wherein item parameters are estimated from empirical data and new responses are generated by sampling abilities from assumed distributions (Baker & Kim, 2004; Harwell, 1997). While conceptually straightforward, this paradigm faces important limitations. Standard IRT models impose rigid assumptions regarding the functional form of item characteristic curves (ICCs), typically relying on logistic or normal ogive functions (Hambleton et al., 1991). These parametric specifications may inadequately represent the complex response processes observed in real assessments, leading to model misspecification and synthetic data that diverge from original distributional features (Junker & Sijtsma, 2001; Sijtsma & Molenaar, 2002).
Standard IRT models traditionally assume strict unidimensionality and conditional independence. While multidimensional IRT theoretically accommodates multiple traits, it requires pre-specifying the number of latent dimensions (Reckase, 1985). Exploratory factor analysis of categorical data (Bartholomew, 1980; Y. Yang & Xia, 2015) and multiple MIRT parameterizations, including compensatory and non-compensatory forms (Wang & Nydick, 2015), offer some flexibility. However, these approaches limit analysis by decomposing item dependencies into a finite set of latent factors. Any residual inter-item covariance falling outside this specified structure is discarded rather than modeled. When data exhibit complex local item dependence (Chen & Thissen, 1997; Yen, 1984), this oversimplified latent representation distorts underlying correlation patterns and violates the local independence assumption (Stout, 1987). Beyond these structural constraints, alternative methods like parametric bootstrapping (Efron & Tibshirani, 1994), multiple imputation (Rubin, 2018), and latent class modeling (Formann, 2007; Vermunt, 2004) struggle to balance flexibility with scalability. Relying on strict distributional assumptions, these approaches fail to capture the complex nonlinear dependencies inherent in large-scale binary response matrices (Chalmers, 2016; Si & Reiter, 2013).
Recent advances in deep learning have introduced flexible, data-driven alternatives for synthetic data generation that relax the rigid assumptions of parametric simulation (LeCun et al., 2015). Deep generative models, including generative adversarial networks (GANs) (I. J. Goodfellow et al., 2014) and variational autoencoders (VAEs) (Kingma & Welling, 2014; D. J. Rezende et al., 2014), have demonstrated the capacity to learn complex, nonlinear dependencies without explicit parametric specification (Xu et al., 2019). However, directly applying these methods to item response data while preserving psychometric properties remains challenging. GANs are often unstable to train and susceptible to mode collapse, resulting in incomplete representation of response pattern variability (Arjovsky et al., 2017; Salimans et al., 2016). Similarly, VAEs typically impose strong distributional assumptions on the latent space that may not align with ability distributions or psychometric constructs (Bowman et al., 2016). In both cases, the absence of an explicit mechanism for preserving marginal item properties means that downstream IRT-based analyses may be compromised, a limitation the present framework directly addresses.
Copula-based modeling, grounded in Sklar’s theorem (Sklar, 1959), offers a complementary framework by decomposing multivariate distributions into univariate marginals and an explicit dependence structure (Joe, 2014; Nelsen, 2006). This separation is particularly well suited to psychometric data; marginal response probabilities can be directly estimated from observed item frequencies, while the copula captures complex dependencies induced by latent traits (Braeken et al., 2007; Nikoloulopoulos & Joe, 2015). Traditional copula approaches in psychometrics have employed parametric copula families such as Gaussian or factor copulas (Kadhem & Nikoloulopoulos, 2023a, 2023b). Recent developments show that neural networks can automate copula construction, substantially improving distributional flexibility without requiring manual specification of parametric copula families (Letizia et al., 2025; R.-S. Yang et al., 2024). As a result, neural network copula (NNC) models can provide a principled mechanism for generating synthetic item response data that preserve both marginal item properties and dependence structures essential for IRT-based analyses.
In this study, we propose an NNC model for generating synthetic dichotomous item response data in educational and psychological assessments. The approach follows a three-stage process: (1) transforming binary responses to pseudo-uniform marginals via randomized probability integral transforms (Genest et al., 2009; Rüschendorf, 2009), (2) learning dependence structures using deep autoencoders (Kingma & Welling, 2014; D. J. Rezende et al., 2014), and (3) generating synthetic data via inverse transformations. By injecting controlled stochasticity, the pseudo-uniform transform resolves the tie-breaking problem inherent in discrete marginals (Genest et al., 2009; Mendes et al., 2007). This ensures that the variates are marginally uniform, fulfilling a prerequisite for Sklar’s theorem (Nelsen, 2006; Sklar, 1959) while preserving inter-item dependence. Critically, item discrimination and difficulty are maintained through the empirical marginal probabilities in the final binary generation step, allowing the design to accommodate the latent variable structure while minimizing distributional assumptions. Finally, to address the inherent risk of distributional divergence and the creation of plausible but statistically unfaithful records (Xu et al., 2019), we utilize a multi-faceted validation framework.
Despite increasing interest in neural synthetic data generation (Choi et al., 2017; Xu et al., 2019), current validation practices often focus on distributional similarity rather than meaningful psychometric criteria (Drechsler & Reiter, 2011). In particular, the reproduction of sampling variability relevant for statistical inference has received little systematic attention (Raab et al., 2016). To address this gap, we conduct an IRT-grounded psychometric validation (Baker & Kim, 2004; Hambleton et al., 1991) evaluating data-level consistency, parameter recovery, and item and test information accuracy. Crucially, we extend standard protocols by comparing empirical asymptotic standard errors with Monte Carlo standard errors (MCSEs) (Robert & Casella, 2004) derived from repeated synthetic generation. This comparative analysis assesses whether the NNC framework preserves both point estimates and the original inferential uncertainty. Through an empirical application to a large-scale numerical reasoning assessment of fluid intelligence, we demonstrate that the proposed approach accurately reproduces essential psychometric properties while protecting examinee anonymity. Generating such structurally faithful synthetic data is critical for intelligence research; operational datasets are rarely shareable due to privacy protocols, though they are essential for developing assessments and benchmarking cognitive measurement models.
2. Method
2.1. Item Response Theory Framework
2.1.1. Two-Parameter Logistic Model
The two-parameter logistic (2PL) model (Birnbaum, 1968) served as the psychometric framework for parameter estimation and validation of psychometric properties. The present framework is scoped to dichotomous (binary) response data. Under the 2PL model, let denote the observed binary response of examinee i () to item k (), where indicates a correct response and indicates an incorrect response. The probability of a correct response for an examinee with latent ability , given item discrimination and difficulty , is specified as:
where represents the latent ability, denotes the discrimination parameter indicating how effectively item k differentiates among ability levels, and represents the difficulty parameter corresponding to the ability level at which the probability of a correct response equals 0.5. The 2PL model relies on three core assumptions: unidimensionality (responses are governed by a single latent trait), local independence (responses are conditionally independent given ), and monotonicity (higher ability increases the probability of success) (Embretson & Yang, 2012; Lord et al., 1968).
2.1.2. Parameter Estimation
IRT parameters were estimated using marginal maximum likelihood (MML) with an expectation-maximization (EM) algorithm (Bock & Aitkin, 1981). The marginal likelihood integrates over the latent ability distribution, defined as:
where denotes the standard normal density representing the population ability distribution. The EM algorithm alternates between computing expected sufficient statistics based on posterior ability distributions (E-step) and updating item parameters to maximize the expected complete-data log-likelihood (M-step) (Baker & Kim, 2004; Bock & Aitkin, 1981).
Following item parameter estimation, individual ability parameters were obtained via Expected A Posteriori (EAP) estimation (Bock & Mislevy, 1982). The EAP method estimates the latent trait as the expected value of the posterior distribution of ability, conditional on the observed response pattern and the estimated item parameters:
where represents the likelihood function and is the standard normal prior. The integrals are approximated using the Gauss–Hermite quadrature (Thissen et al., 1995). EAP estimation was selected because it minimizes mean squared error over the population and yields stable, finite estimates even for extreme response patterns, for which maximum likelihood estimates are undefined (Bock & Mislevy, 1982; Thissen et al., 2001).
2.2. Neural Network Copula Methodology
This section outlines the proposed NNC framework for modeling binary item response data. The complete algorithmic procedures for model training and synthetic data generation are detailed in Appendix A.
2.2.1. Copula Theoretical Foundation
Copula theory provides the mathematical foundation for our approach by enabling the separation of marginal distributions from dependence structures (Nelsen, 2006; Sklar, 1959). Sklar’s theorem establishes that any multivariate distribution function F can be uniquely decomposed as:
where are univariate marginal cumulative distribution functions and is the copula function capturing the dependence structure (Sklar, 1959). This decomposition is particularly valuable for psychometric data: marginal response probabilities can be directly estimated from observed frequencies, while the copula C encodes complex dependencies induced by the underlying latent structure without requiring explicit specification of the latent variable model (Braeken et al., 2007; Fox & Marianti, 2016; Nikoloulopoulos & Joe, 2015).
For discrete binary data, we employ a pseudo-copula approach via the randomized probability integral transform (Genest et al., 2009; Rüschendorf, 2009). Given binary responses with marginal probability , we construct pseudo-uniform variates as:
This stochastic transformation ensures that marginally while preserving the underlying dependence structure, yielding a pseudo-uniform matrix suitable for copula modeling (Genest et al., 2009).
It is important to clarify what this transformation does and does not do, as the role of the pseudo-uniform step within the broader pipeline can be misread. Equation (5) is a standard preprocessing technique required by Sklar’s theorem when the response variables are discrete. Because discrete distributions have no unique copula representation without a continuity correction, the randomized probability integral transform resolves the tie-breaking problem by injecting controlled stochasticity, ensuring that the transformed variates are marginally uniform (Genest et al., 2009; Mendes et al., 2007; Rüschendorf, 2009). Crucially, this step does not replace the IRT model, nor does it discard information about item discrimination (ICC steepness) or difficulty. Those psychometric quantities are preserved through the empirical marginal probabilities , which govern the final binary generation step in Equation (12). Unlike deterministic transformations that can introduce artifacts at boundaries, this randomized approach maintains distributional properties essential for accurate dependence modeling (Rüschendorf, 2009).
2.2.2. Deep Autoencoder Architecture
The NNC employs an encoder–decoder architecture designed to isolate and learn the latent dependence structure underlying the item responses. Functionally, the encoder serves as a non-linear feature extraction mechanism, mapping the observed pseudo-uniform variates to a latent space via:
where is the i-th row of the pseudo-uniform matrix , and represents the latent code. By compressing the input, the encoder forces the model to capture the essential covariance structure of the data rather than simply memorizing individual response patterns.
Conversely, the decoder acts as the generative component, reconstructing the uniform marginals from these latent codes:
where denotes the decoder parameters. This reconstruction process ensures that the latent codes retain sufficient information to recover the original multivariate distribution.
Our implementation employs a multi-layer feedforward architecture to approximate these complex mappings (Hinton & Salakhutdinov, 2006). The encoder comprises three hidden layers with dimensions [256, 128, 64]. This decreasing architecture creates a hierarchical compression funnel. By initializing with a high-capacity layer, the network can capture broad, non-linear associations among items, while the subsequent progressive reduction forces the model to distill these interactions into increasingly abstract representations, thereby minimizing the information loss often associated with abrupt dimensionality reduction (I. Goodfellow et al., 2016).
Each layer utilizes rectified linear unit (ReLU) activation, (Glorot et al., 2011; I. Goodfellow et al., 2016), to model non-linear interactions between items. To ensure convergence and generalization, we apply batch normalization (Ioffe & Szegedy, 2015) to stabilize internal covariate shifts and dropout regularization (rate 0.2) (Srivastava et al., 2014) to prevent co-adaptation of neurons. The final encoder layer projects to d latent dimensions without activation, allowing the latent space to span the full real number line. The specific value of this dimensionality parameter, d, is determined via sensitivity analysis to balance reconstruction fidelity, dependence preservation, and model parsimony (see Section 4.1). The decoder mirrors this architecture in reverse but concludes with a sigmoid output activation, . This final activation is critical for the copula framework, as it strictly constrains the reconstructed outputs to the unit interval , preserving the probabilistic interpretation of the uniform marginals required by Sklar’s theorem. This sigmoid constraint is a standard architectural choice for autoencoder outputs bounded to (I. Goodfellow et al., 2016) and is functionally distinct from the logistic ICC in Equation (1), which models item response probabilities as a function of ability.
2.2.3. Training Objective
The model optimizes a composite loss function designed to simultaneously learn the dependence structure while strictly enforcing the distributional constraints required by Sklar’s theorem:
The primary component, reconstruction loss (), quantifies the autoencoder’s ability to compress and recover the multivariate dependence structure. We minimize the mean squared error between the input pseudo-uniform variates and the reconstructed outputs:
By minimizing this error, the model is forced to encode the essential inter-item correlations into the latent space .
The secondary component, marginal preservation loss (), acts as a regularizer to prevent “marginal collapse,” where the model might drift away from the required uniform distribution to minimize reconstruction error. This term penalizes deviations of the reconstructed column means from the theoretical expectation of a distribution (which is 0.5):
Ensuring that anchors the generator to the correct marginal domain, which is critical for the subsequent inverse probability integral transform. The weighting parameter was empirically selected to balance these objectives. It provides sufficient regularization to maintain distributional properties without overpowering the gradient signal needed to learn complex dependencies (I. Goodfellow et al., 2016). Model training employed the Adam optimizer (Kingma & Ba, 2015) with an initial learning rate and a mini-batch size of 64. To ensure convergence to a stable minimum, learning rate scheduling via “ReduceLROnPlateau” reduced the rate by 50% when validation loss plateaued for 10 consecutive epochs. Training continued until validation loss failed to improve for 20 consecutive epochs (early stopping), ensuring the retention of the generalizable model configuration (Prechelt, 1998).
2.2.4. Synthetic Data Generation
Synthetic data generation proceeds through a four-stage pipeline designed to operationalize the learned copula model while preserving the complex distributional features of the latent space. First, latent representations extracted via the encoder are modeled using non-parametric kernel density estimation (KDE). This choice addresses the shrinking phenomenon often observed in deterministic autoencoder latent spaces, where parametric (e.g., Gaussian) assumptions can underestimate the density of extreme scores (Schmidt & Stadtmüller, 2006). The empirical distribution of latent codes () is estimated as:
where are the training data latent vectors, is the standard Gaussian kernel, and d is the dimensionality of the latent space.
The bandwidth parameter h controls the smoothness of the estimated density and directly affects tail preservation in the synthetic data. Although h can be optimized via cross-validation to maximize held-out log-likelihood (Scott, 2015), in practice it is selected to balance the tradeoff between bias and variance in the latent distribution. In the present study, h is determined through a structured sensitivity analysis (see Section 4.1), evaluating its impact on dependence preservation and psychometric recovery. Specifically, the latent codes exhibited moderate variance with meaningful tail density corresponding to high- and low-ability examinees. A bandwidth in the range of h = 0.2 to 0.3, relative to the data-adaptive Silverman rule-of-thumb estimate of , mitigates over-smoothing and ensures better preservation of extreme scores in the synthetic output, which is critical for accurately capturing extreme ability levels in cognitive assessment contexts (Silverman, 1986).
Following distribution characterization, synthetic generation proceeds by sampling new latent codes directly from the estimated density . These sampled codes are mapped back to the pseudo-uniform space via the decoder, where the sigmoid activation ensures values remain within . To recover the discrete binary format, these continuous probabilities are subjected to an inverse probability integral transform:
where denotes the indicator function and represents the empirical marginal probability observed in the training data. This thresholding mechanism guarantees that , thereby preserving item difficulty by construction (Genest et al., 2009). Crucially, this pipeline effectively decouples the modeling of complex dependence structures (managed by the neural network and KDE) from the preservation of marginal properties, leveraging the core advantage of the copula framework to ensure psychometric validity (Nelsen, 2006; Sklar, 1959).
2.3. Validation Metrics and Criteria
To evaluate the utility of the proposed NNC for synthetic item response data, we employed a multi-faceted validation framework following established IRT validation practice (Baker & Kim, 2004; Hambleton et al., 1991). The framework is organized into four complementary facets, specifically data-level consistency, psychometric properties, statistical inference precision, and algorithmic stability.
2.3.1. Data-Level Consistency
The evaluation of data-level consistency focused on whether the synthetic data preserved statistical features of the original response matrix. First, generative quality at the respondent level was validated by comparing observed total score distributions. Second, univariate difficulty hierarchies were evaluated by contrasting the proportion of correct responses (marginal probability) for each item in the real data () against the synthetic data (). Linear agreement was assessed via Pearson correlation (r), and the magnitude of deviation was quantified using the mean absolute deviation (MAD):
MAD was preferred over RMSD for marginal probabilities because it provides an interpretable average absolute discrepancy on the original probability scale, without disproportionate influence from items with large individual deviations; RMSD is reported for IRT parameters, where sensitivity to outlying items is more diagnostically relevant.
Third, dependencies were assessed by computing pairwise inter-item correlation matrices for both datasets. The discrepancy between the matrices was quantified using the root mean square residual (RMSR):
where represents the Pearson correlation between items k and l.
2.3.2. Psychometric Properties
This dimension assesses whether the synthetic data maintains the structural and measurement characteristics essential for IRT-based inference. First, the consistency between IRT parameters estimated from synthetic data () and empirical data () was evaluated. Rank-order preservation was quantified using Pearson correlation coefficients (r). The magnitude of parameter discrepancy was evaluated using the MAD and the root mean squared deviation (RMSD):
These metrics were computed separately for discrimination (a) and difficulty (b) parameters. Additionally, the consistency of the latent trait distributions was evaluated by comparing kernel density estimates of the EAP ability scores () derived from both datasets.
Second, to assess precision across the latent trait continuum, item information functions (IIF), test information functions (TIF), and conditional standard errors of measurement (CSEM) were computed over a uniform grid of 100 points, . For the 2PL model, the information contributed by item k is defined as:
where is the item response function. The term is the Bernoulli variance of the item response, reflecting maximum information where response probability is most uncertain (i.e., near ). The aggregate TIF was calculated as . Consistency was quantified by calculating the Pearson correlation (r) between the real and synthetic TIF vectors, as well as between the CSEM vectors, across the evaluation grid.
Third, to verify probabilistic plausibility of the generated response patterns, Infit and Outfit mean square (MNSQ) statistics were computed based on standardized residuals (Hambleton et al., 1991; Wright & Stone, 1979). The Infit statistic weights residuals by their variance, making it sensitive to unexpected response patterns when the examinee’s ability is close to the item difficulty, while the Outfit statistic is an unweighted mean square sensitive to unexpected responses far from an examinee’s ability level:
where represents the Bernoulli variance of the binary response. Values within the acceptable range indicate adequate fit (Wright & Stone, 1979), while values below 0.5 indicate severe under-dispersion. The correspondence between the fit profiles of the real and synthetic data was assessed to ensure the generative model did not introduce aberrant response patterns (over-dispersion) or artificially deterministic dependencies (under-dispersion).
2.3.3. Statistical Inference Precision
To assess whether the synthetic data appropriately reproduced sampling variability, we conducted a Monte Carlo analysis with independent synthetic data generations. The MCSE for each parameter was computed as:
Inferential validity was evaluated by comparing these MCSEs against the asymptotic standard errors (ASE) derived from the real data. The ASE for the item parameter vector is calculated as the square root of the diagonal elements of the inverse Fisher information matrix (Baker & Kim, 2004):
The ratio serves as the primary inferential validity index, with values near 1.0 indicating that the synthetic data reproduces the precision of the real data, values above 1.0 indicating conservative standard errors, and values below 1.0 indicating over-smoothing of sampling variability. It is important to note that model-based ASEs often underestimate uncertainty in empirical data due to inevitable model misspecification. Consequently, discrepancies where may reflect the synthetic data capturing full generative variability rather than a deficiency in precision.
2.3.4. Algorithmic Stability
The preceding three facets assess the fidelity of synthetic data produced by a single trained model. Algorithmic stability addresses a distinct and complementary question: whether the results are reproducible across different random initializations of the neural network. This confirms that the observed fidelity reflects a stable structural representation of the data rather than a fortunate outcome of a particular optimization trajectory. To quantify stability, the complete training and generation pipeline is repeated across multiple independent execution runs, each utilizing a distinct random seed. For every iteration, the NNC is retrained from scratch to generate a new synthetic dataset. By evaluating the variance of the primary validation metrics across these independent runs, we can determine the robustness of the model. A low variance across executions indicates that the NNC converges to an equivalent generative solution regardless of initialization, satisfying the reproducibility requirement for practical deployment.
3. Analysis
3.1. Analytical Framework
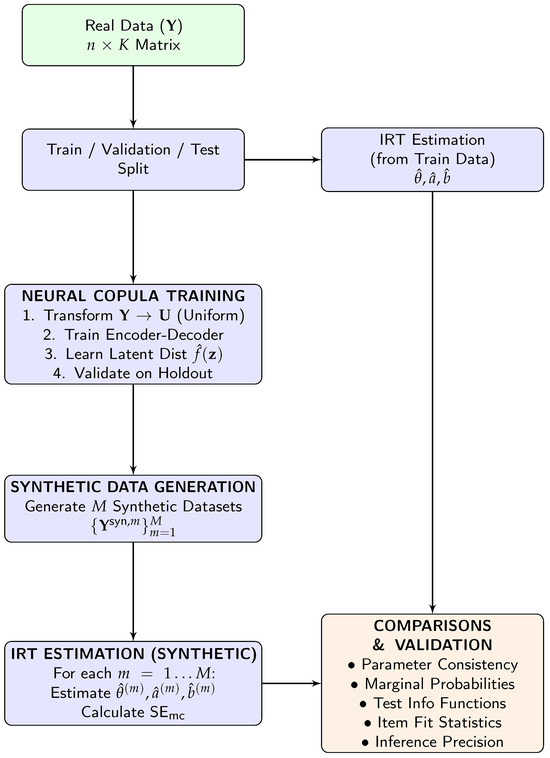
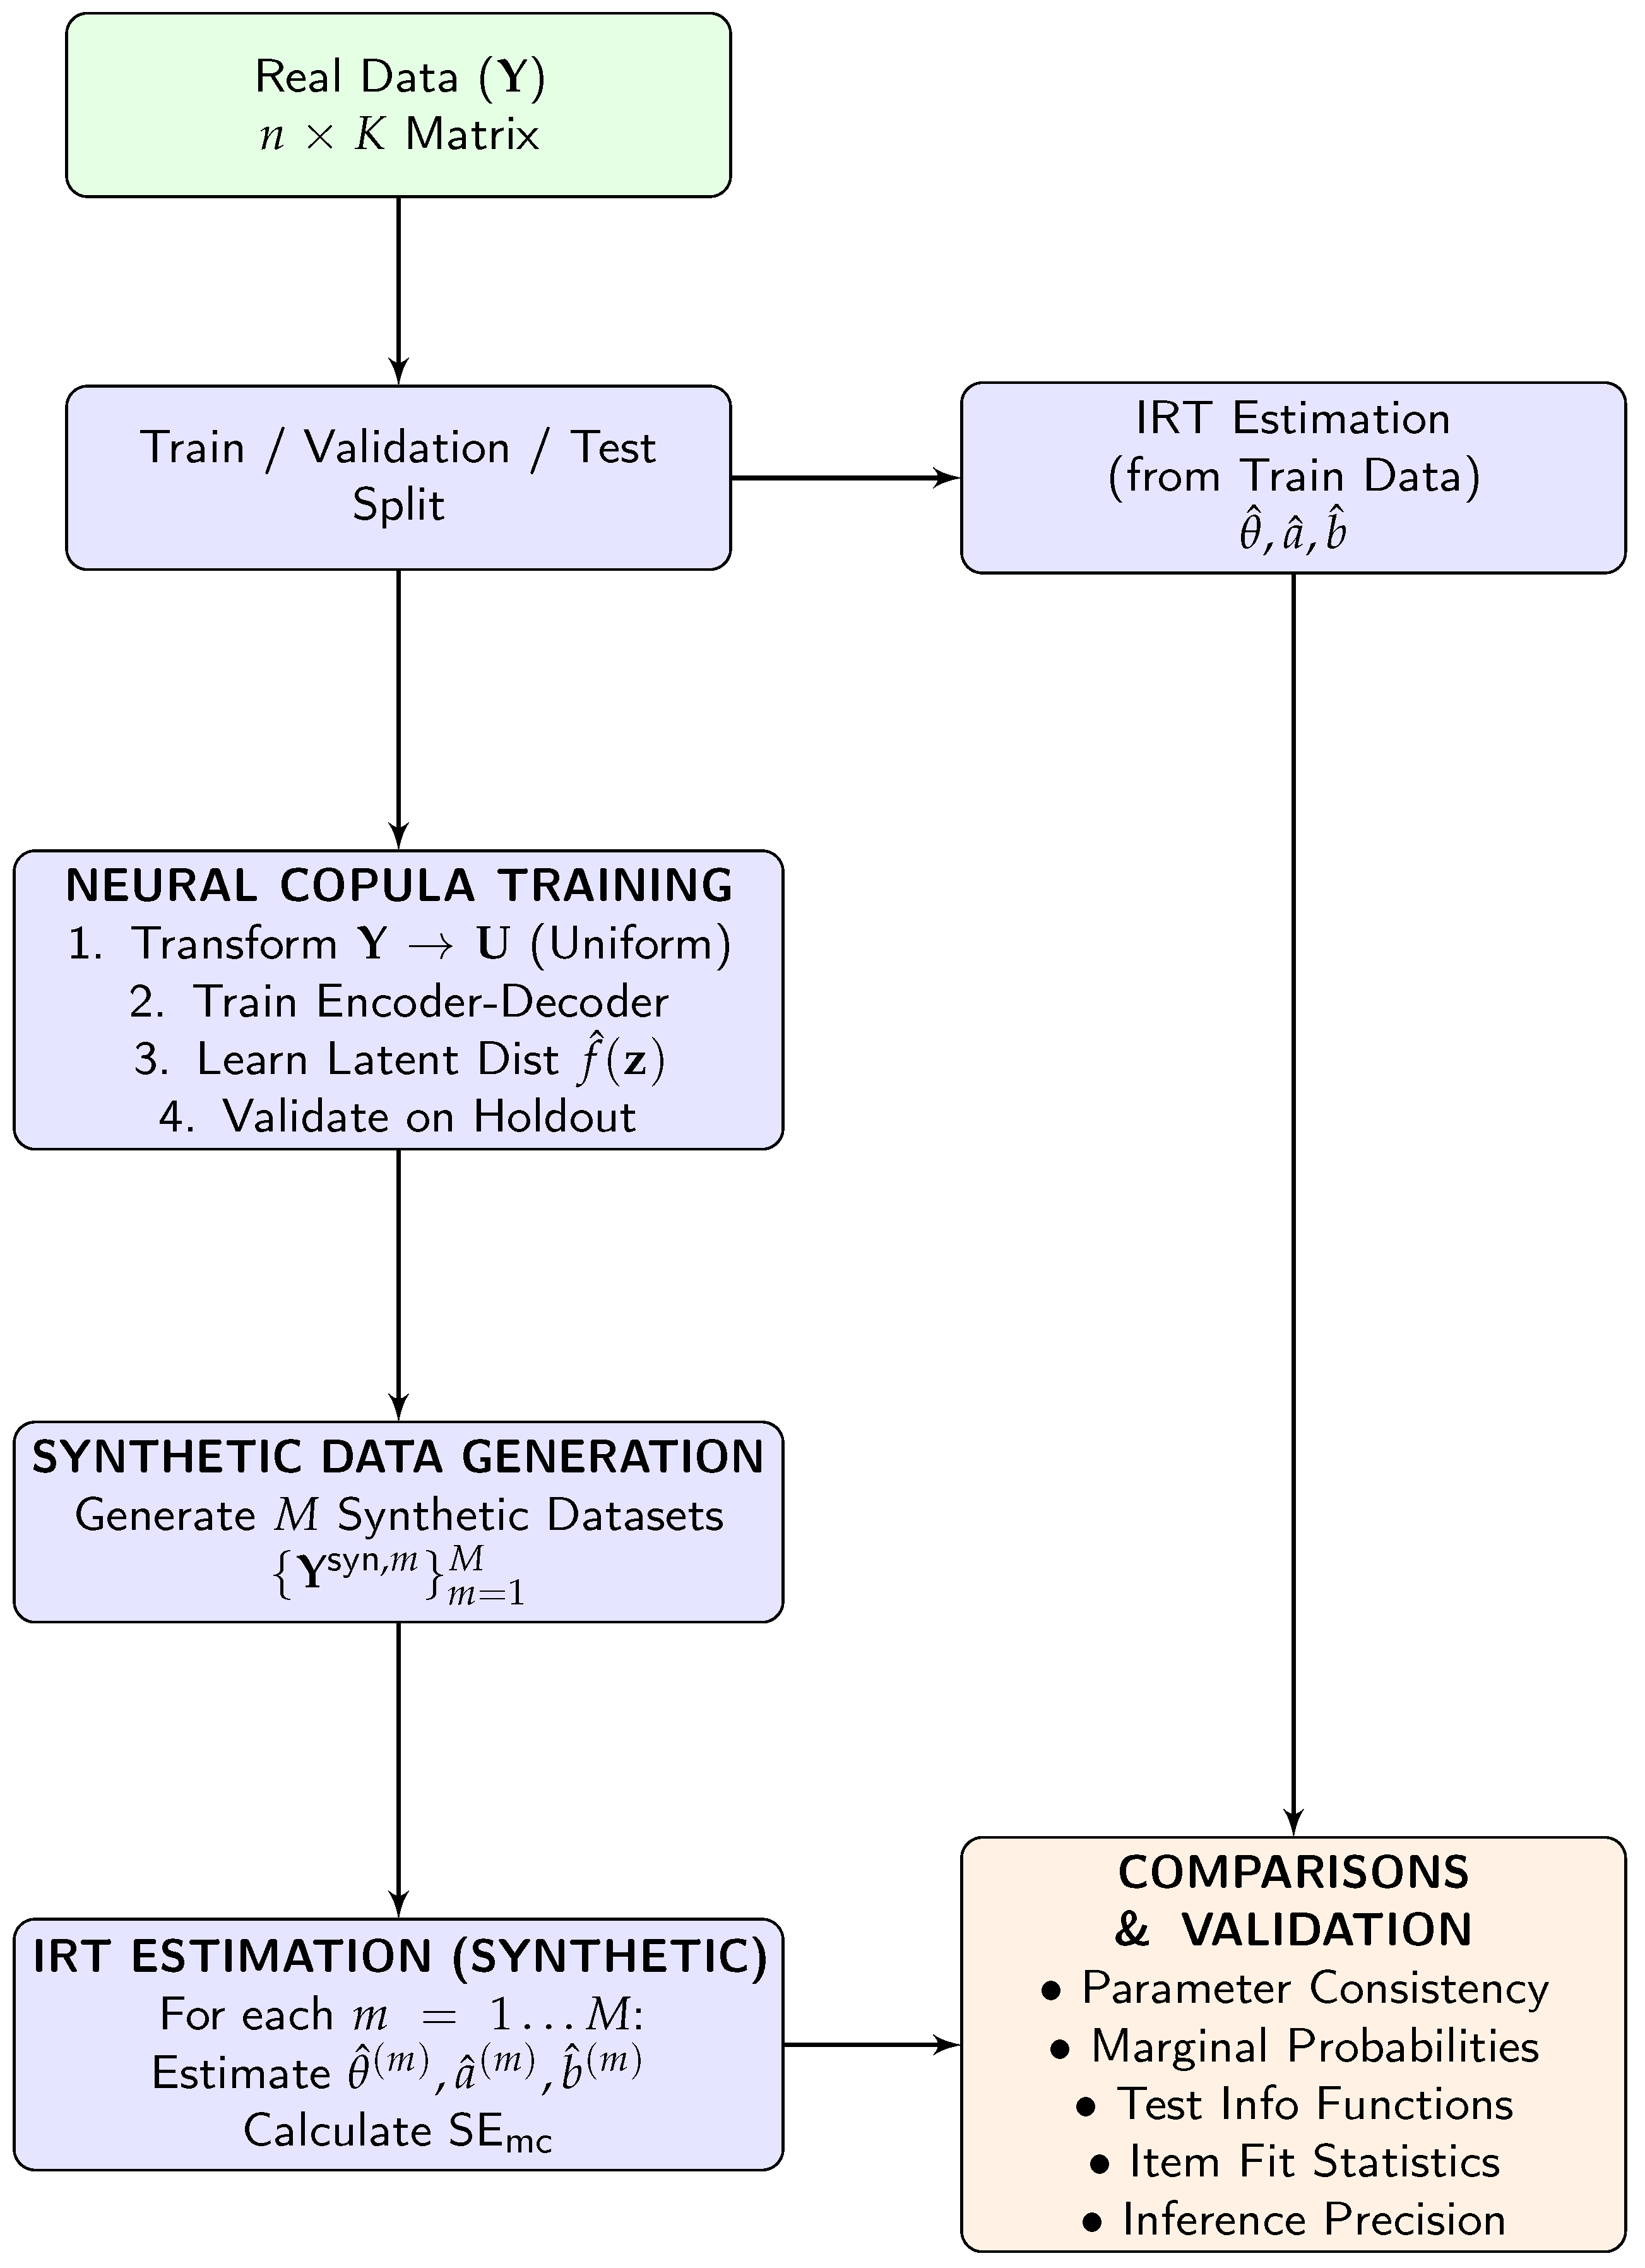
The analytical pipeline (Figure 1) employs the four-facet validation framework described in Section 2.3 to assess NNC synthetic data for IRT applications in assessment. After conducting a sensitivity analysis using 50 synthetic replications per configuration to establish the optimal latent dimensionality (d) and kernel density bandwidth (h), we structured the evaluation across the four validation facets. Table 1 summarizes the specific dataset allocations and random seed configurations utilized for each facet. To ensure reproducibility, the complete implementation code and sampled dataset are publicly available at https://github.com/Ju-youngJung/Neural-Network-Copula-Synthetic-Data.git (accessed on 14 April 2026).
Figure 1.
Flowchart of the Neural Network Copula analysis pipeline for synthetic data.
Table 1.
Summary of synthetic dataset allocation and seed configuration across the four validation facets.
The data-level consistency and psychometric property evaluations utilize a single primary synthetic dataset generated with a fixed seed of 42. Benchmark real parameters were estimated from the training data partition () via MML estimation for the 2PL model using the girth 0.8.0 of the Python 3.11 package (Sanchez, 2021). At the data level, this single dataset supports the analysis of total score distributions, marginal probabilities, and inter-item correlations. At the psychometric level, this exact same dataset is reused to estimate IRT parameters (a, b), ICCs, TIF, CSEM, and item fit statistics. To distinguish generative model uncertainty from sampling variability (Robert & Casella, 2004), the statistical inference precision facet generates independent datasets using derived child seeds from the master random number generator.
Each dataset matches the training sample size (). This volume ensures sufficient convergence of the MCSE estimator in Equation (20) (Koehler et al., 2009) while maintaining computational feasibility. IRT parameters are re-estimated for each replication to compute the MCSE per item, which is then compared against the asymptotic standard error via Equation (21). A ratio of near 1.0 indicates that the synthetic data replicate the inferential precision of the original data, with ratios above 1.0 indicating conservative uncertainty and ratios below 1.0 indicating potential over-smoothing. The algorithmic stability facet restarts the entire pipeline from scratch across five distinct seeds (101, 202, 303, 404, 505). For each seed, the NNC is retrained from a random initialization, and one synthetic dataset is generated to confirm that parameter consistency metrics remain stable across optimization trajectories. The mean and standard deviation of , , and are reported to quantify sensitivity to random initialization.
3.2. Data Source and Partitioning
The empirical analysis utilized item response data from a large-scale high school mathematics assessment measuring numerical reasoning ability, a construct closely related to fluid intelligence and general cognitive ability. The dataset comprised binary responses (0 for incorrect, 1 for correct) from examinees across items, yielding a response matrix measuring a single latent ability construct consistent with the unidimensional 2PL model. Due to privacy protocols governing the operational records, the associated GitHub, repository provides a randomly sampled dataset of 3000 examinees for public replication. To separate optimization from evaluation while preserving the total score distribution, we partitioned the full operational data into three mutually exclusive subsets via stratified random sampling by score decile. These subsets included a training set (64%, ) to fit the NNC model and estimate benchmark IRT parameters, a validation set (16%, ) for hyperparameter tuning and early stopping, and a test set (20%, ) for out-of-sample verification. Primary psychometric comparisons evaluated synthetic data generated from the model trained on directly against this identical training partition. Estimating both the benchmark IRT parameters and the NNC model from the exact same data ensures a fair evaluation of generative fidelity independent of train and test distributional shifts.
4. Results
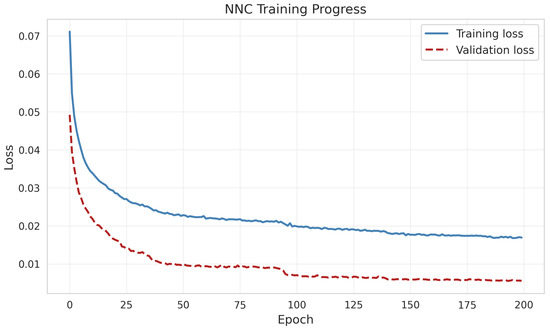
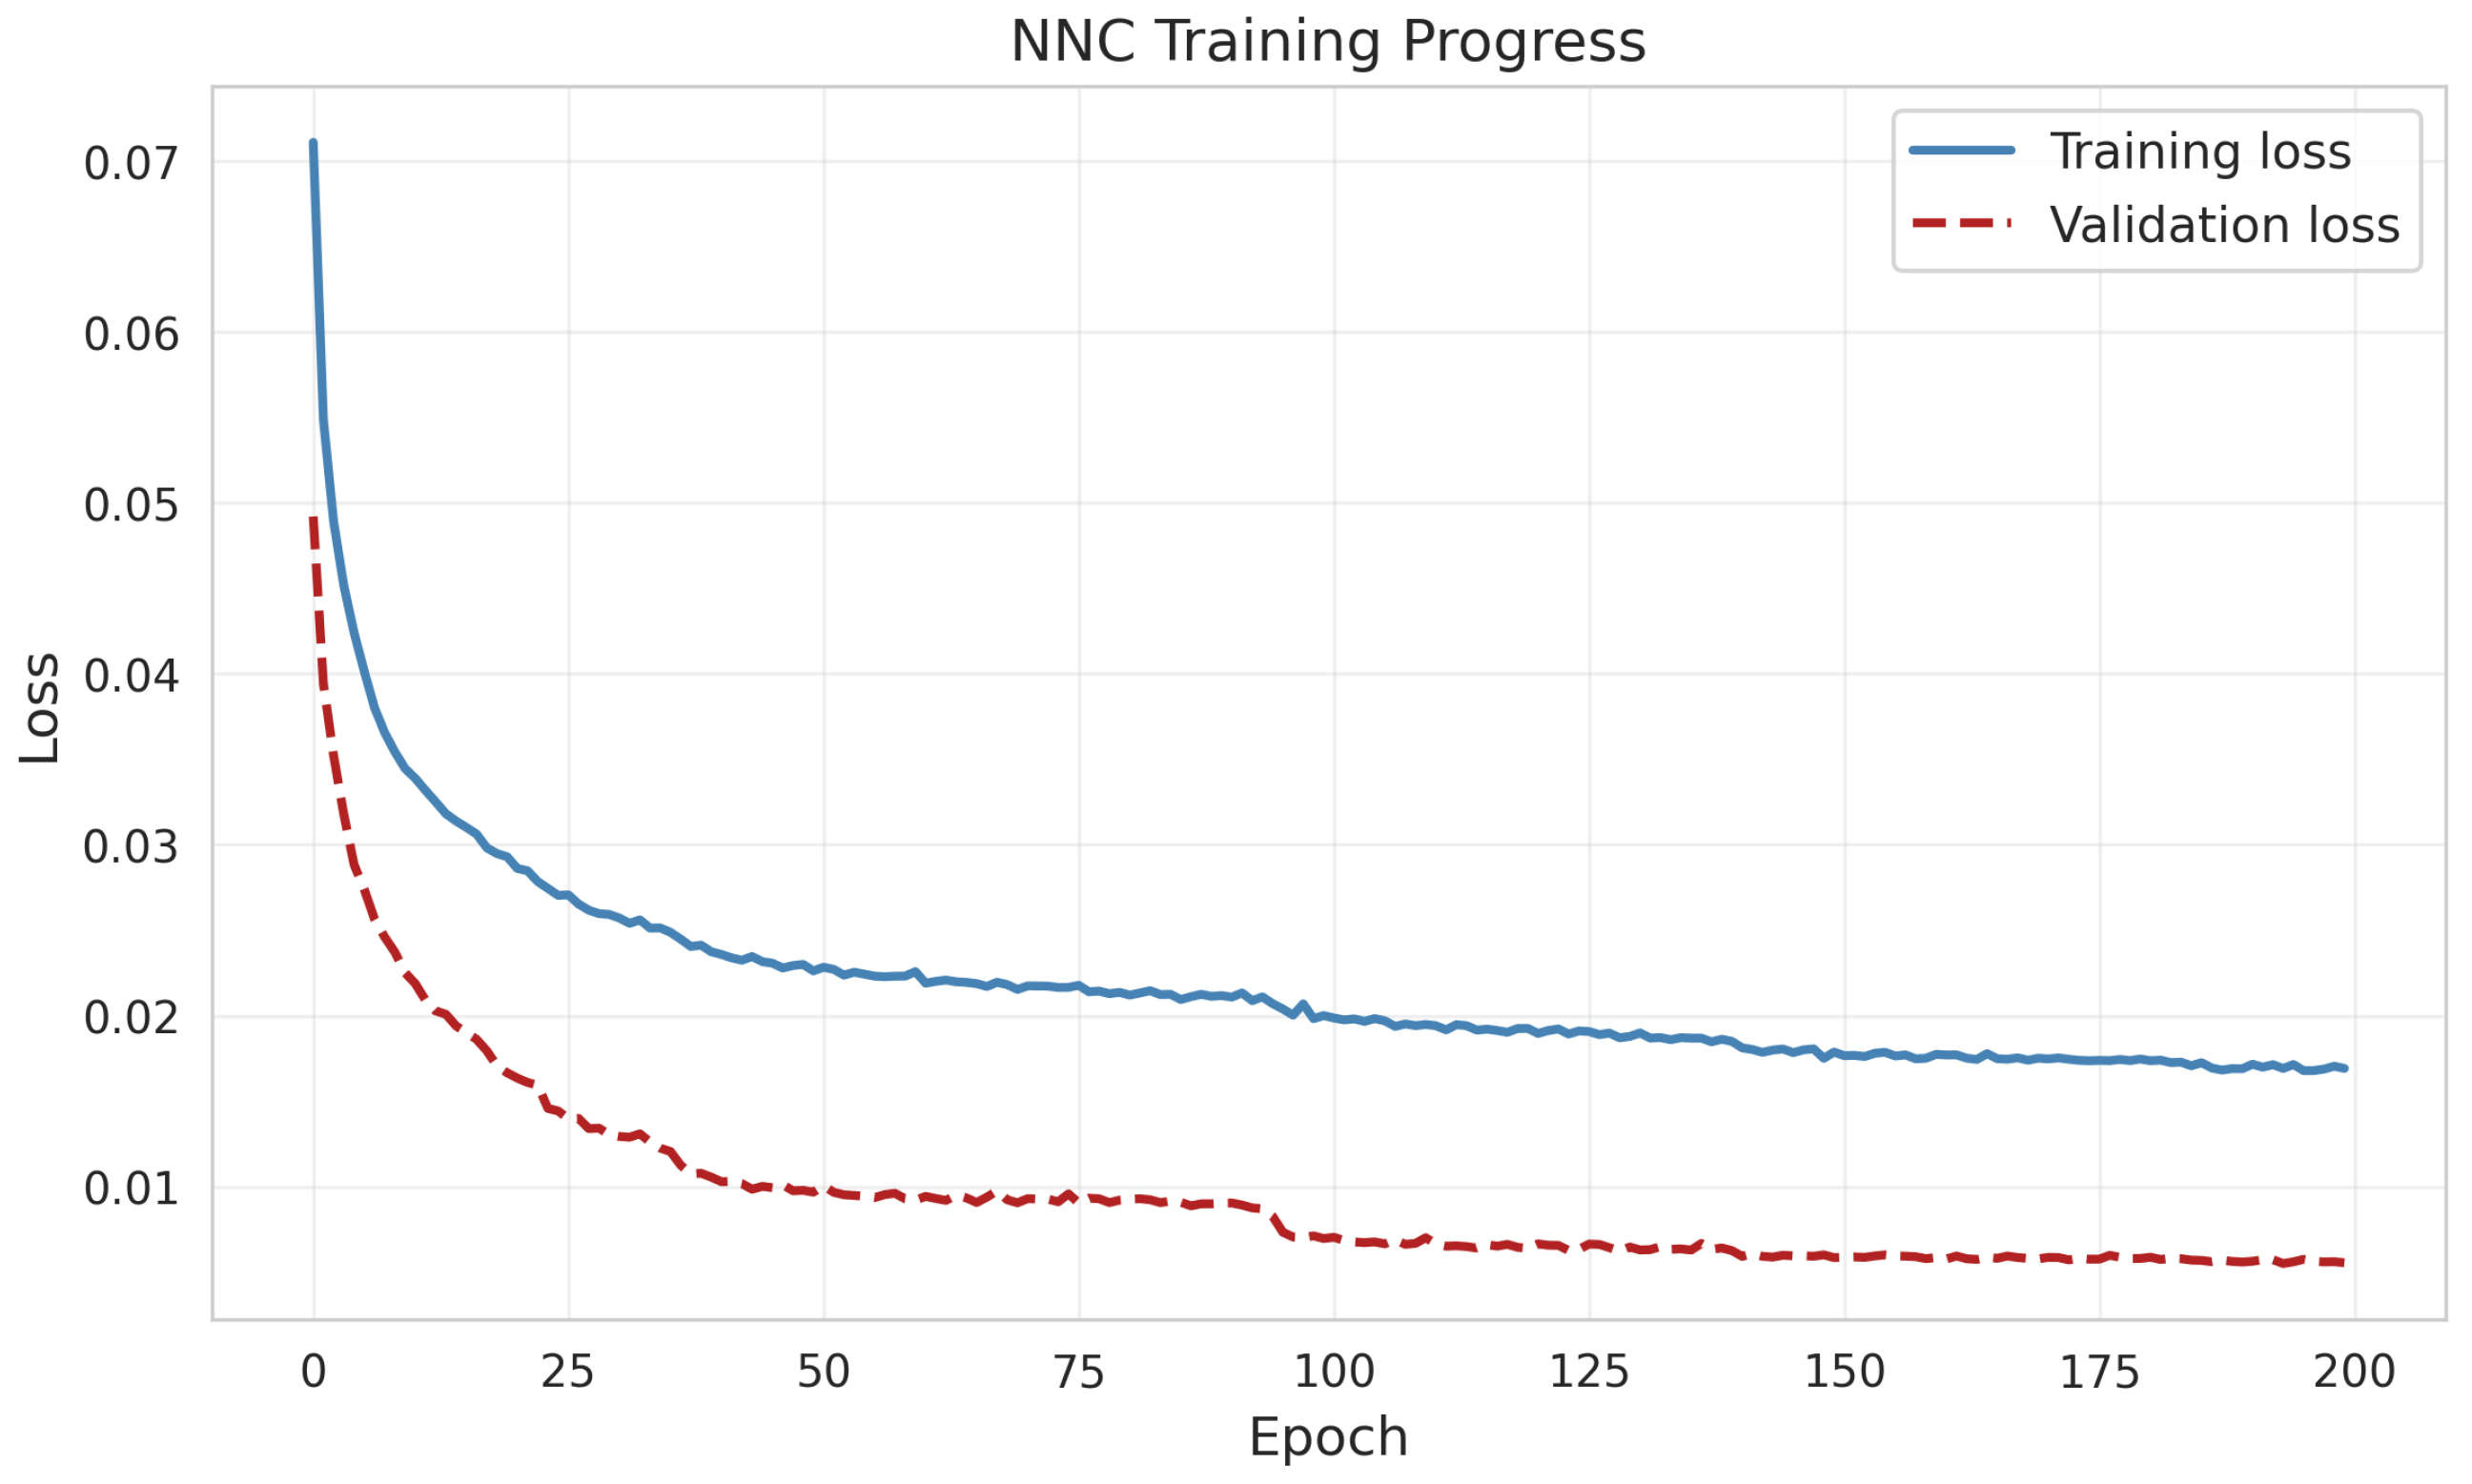
All computations utilized PyTorch 1.12 (Paszke et al., 2019) within an environment featuring 32 CPU cores and a dedicated NVIDIA L40S GPU with CUDA acceleration. Training the model on the full dataset (, ) to convergence required 679.4 s (approximately 11.3 min). Once trained, generating the primary synthetic dataset took only 0.02 s. Completing the Monte Carlo replications for standard error estimation required 367.4 s (approximately 6.1 min). Figure 2 illustrates the convergence trajectory of the composite loss function during training. Both the training and validation loss decreased rapidly within the first 50 epochs and stabilized thereafter, reaching a clear plateau by approximately epoch 150. The consistent alignment between the two curves indicates that the NNC successfully learned the underlying dependence structure of the response data without overfitting or optimization instability.
Figure 2.
Neural Network Copula training progress. The plot shows the minimization of training loss (blue, solid) and validation loss (red, dashed) over 200 epochs.
4.1. Sensitivity Analysis
We selected latent dimensions to optimize the balance between reconstruction fidelity and parsimony (Table 2). The candidate set was chosen to span a range from under-parameterized to over-parameterized representations relative to the number of observed items (). Specifically, represents a compressed latent space (approximately half of K), which tests the risk of information loss, whereas and exceed the observed dimensionality and allow evaluation of potential overfitting and redundancy in the latent representation. This range ensures that the selected dimensionality is not driven by an arbitrary choice but reflects a principled exploration of model capacity.
Table 2.
Sensitivity of validation metrics to latent dimension (d) and kernel density estimation bandwidth (h).
Evaluating a validation set across using synthetic replications per configuration revealed that caused over-compression, severely degrading (0.032) and RMSR (0.065) despite yielding the highest (0.980) and a relatively lower (0.988) compared to higher dimensions. Among higher dimensions, achieved the highest (0.942) with , while maintaining an excellent (0.015) and RMSR (0.030) comparable to . Notably, remained stable at 0.996 across all , indicating that difficulty parameter recovery is robust to latent dimension choice within this range, whereas showed greater sensitivity. This configuration naturally bounds model capacity to one coordinate per item (), relying on dropout and batch normalization to prevent trivial identity mapping.
For KDE, we employed a fixed bandwidth of to preserve meaningful tail densities for extreme scores. The candidate set was selected to represent a spectrum of smoothing levels, ranging from low smoothing (capturing fine-grained local structure) to high smoothing (emphasizing global density structure). In particular, allows evaluation of potential high-variance, under-smoothed estimates, whereas tests the impact of aggressive smoothing that may obscure inter-item dependencies. Intermediate values (h = 0.2, 0.3) provide practical trade-offs commonly recommended in the kernel density estimation literature.
Sensitivity evaluations across , also averaged over replications, confirmed this choice. Across all bandwidth values, remained highly stable (0.995–0.996), while ranged from 0.949 to 0.973 and RMSR varied more substantially. While overall performance remained stable for values up to , the widest bandwidth () over-smoothed the inter-item dependence structure, resulting in a substantially higher RMSR (0.070). Ultimately, yielded the optimal balance with the lowest RMSR (0.025), , and a of 0.016.
4.2. Data-Level Fidelity
4.2.1. Total Score Distribution
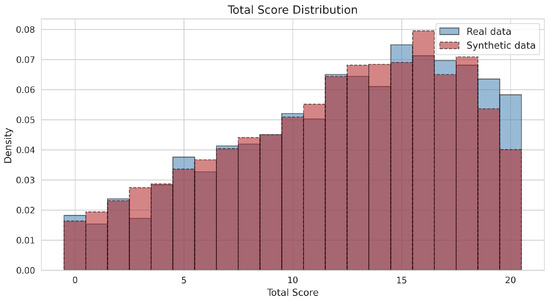
Generative quality at the respondent level was evaluated by comparing the distribution of observed total scores. As illustrated in Figure 3, the NNC accurately reproduced the distributional shape, central tendency, and dispersion of the empirical scores. The synthetic data closely matched the real data in terms of mean total score ( versus ) and standard deviation ( versus ). The synthetic distribution (red, dashed) closely overlaps with the real distribution (blue, solid), successfully capturing the distinct negative skewness (Skewnesssyn = −0.441 versus Skewnessreal = −0.459) and kurtosis (Kurtosissyn = −0.764 versus Kurtosisreal = −0.735), as well as density peaks in the upper score range (scores 15 to 19). However, the synthetic data exhibited a slight underrepresentation of the maximum possible score (20), only partially capturing the frequency of perfect scores in the empirical data. This boundary effect is consistent with the known tendency of fixed-bandwidth KDE to underestimate density at distributional boundaries (Jones, 1993).
Figure 3.
Comparison of observed total score distributions for real (blue, solid) and synthetic (red, dashed) data.
4.2.2. Marginal Probabilities
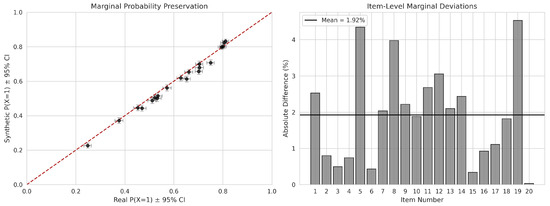
Item-level difficulty hierarchies were evaluated by contrasting the proportion of correct responses (). Figure 4 (left panel) presents a scatter plot of these probabilities, revealing a strong linear relationship where points lie almost precisely on the identity line (). This indicates that the NNC maintained the rank-order difficulty of items, successfully distinguishing between easy items (Item 13, ) and difficult items (Item 09, ). As detailed in Table 3 and visualized in Figure 4 (right panel), the across all 20 items was 0.019, with a maximum absolute difference of 0.045 for Item 19. The mean relative error of 3.398% demonstrates that univariate statistical features were preserved with high consistency. The right panel also displays bootstrap 95% confidence intervals computed from 1000 resamples of the training data; synthetic marginals fall within these intervals for all but one item, confirming that observed deviations are within expected sampling variability.
Figure 4.
Consistency of marginal probabilities. The left panel illustrates the preservation of item difficulties relative to the identity line (red, dashed). The right panel quantifies absolute deviations per item with bootstrap 95% confidence intervals (whiskers) derived from 1000 resamples of the training data.
Table 3.
Comparison of real and synthetic marginal probabilities ().
4.2.3. Pairwise Associations
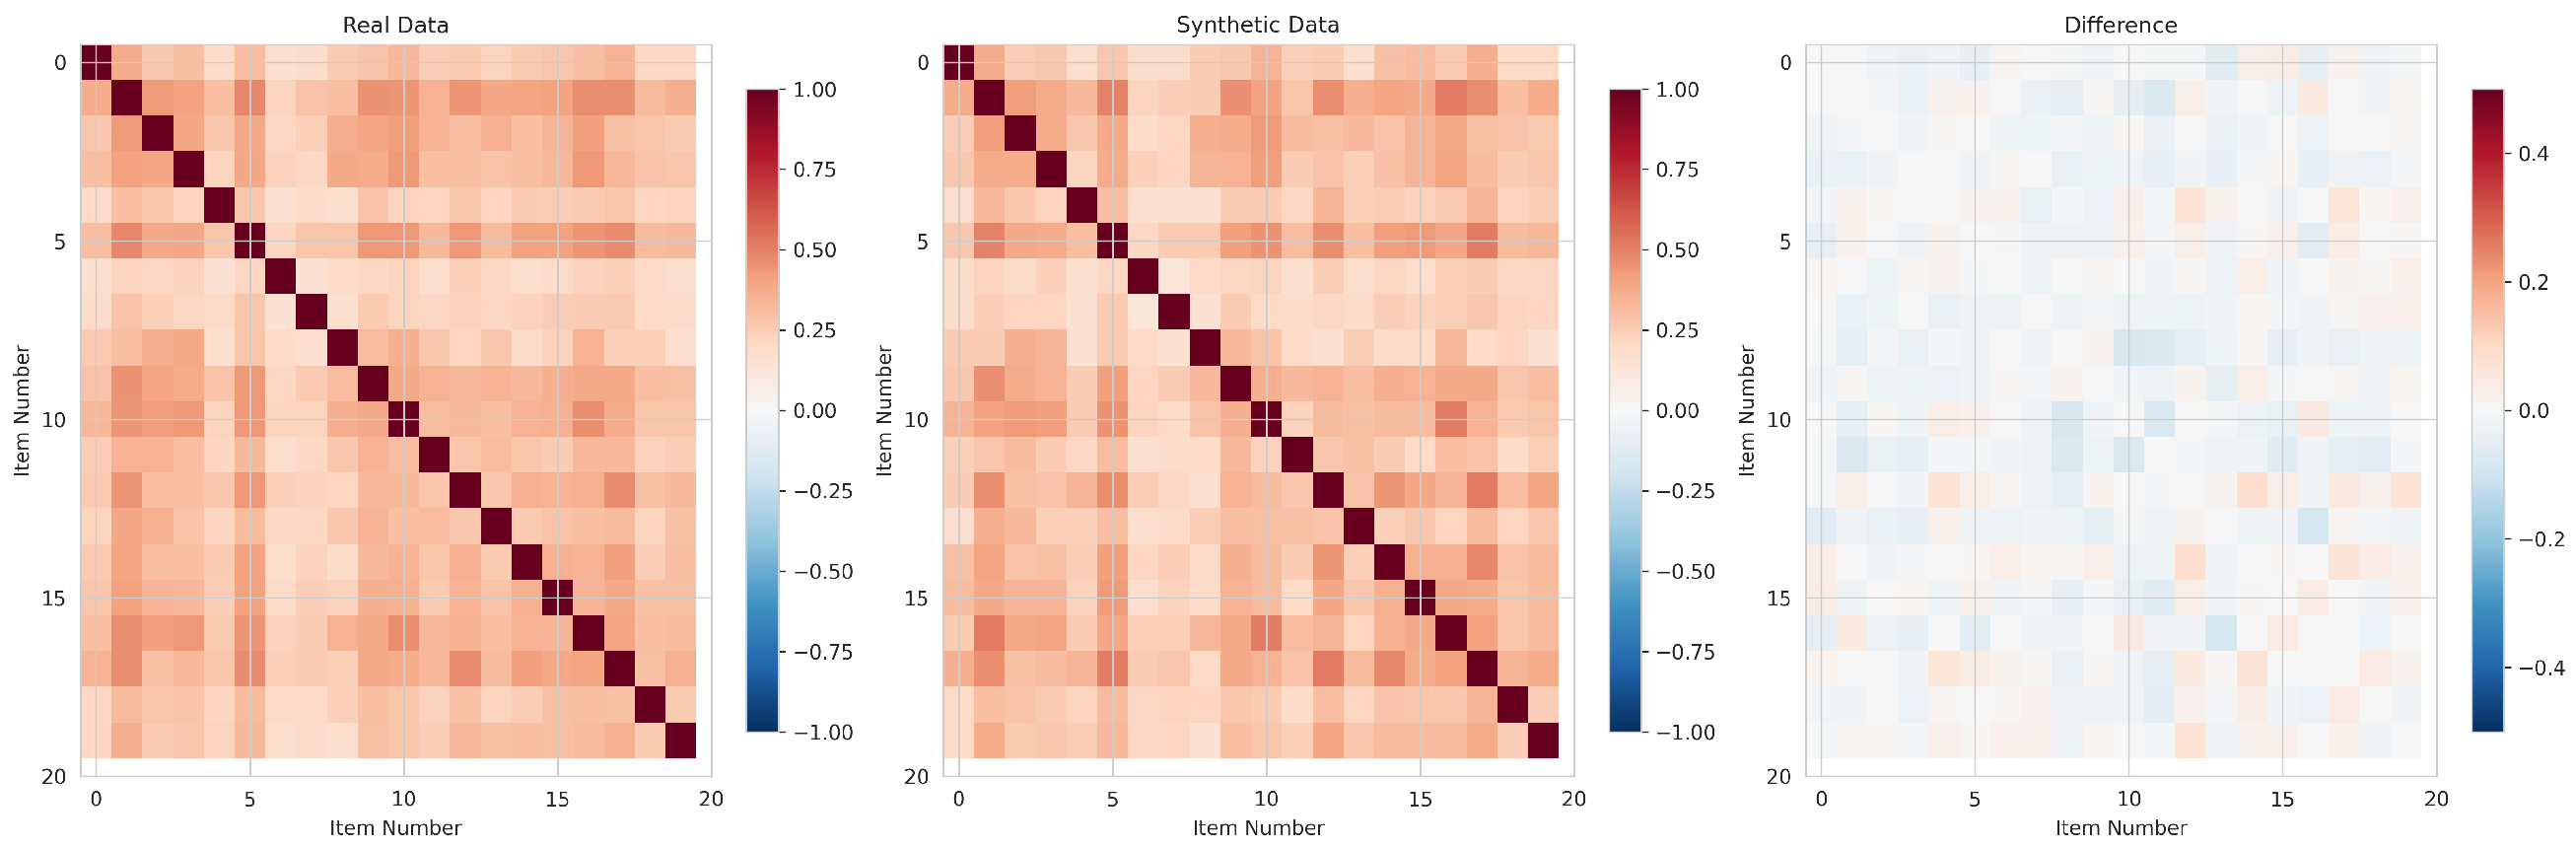
The preservation of higher-order dependencies was assessed by examining the inter-item correlation structures. Figure 5 presents the correlation matrices for the real data (left) and synthetic data (middle), alongside the difference matrix (right). Visual inspection confirms that the synthetic data accurately replicated the block-diagonal structure and intensity of the empirical correlations. The difference heatmap is predominantly neutral, indicating residuals close to zero and devoid of systematic bias. Quantitatively, this structural fidelity was confirmed by a low RMSR (0.032; values below 0.05 are generally considered indicative of good fit (Hu & Bentler, 1999)), validating that the NNC effectively preserved the local dependence structure required for accurate psychometric dimensionality assessment.
Figure 5.
Inter-item correlation heatmaps for real data (left), synthetic data (middle), and their difference (right). Each panel uses an identical colour scale. The colour scale for the difference matrix (right) ranges from −0.4 (blue) to +0.4 (red).
4.3. Psychometric Parameter Recovery
4.3.1. IRT Parameter Consistency
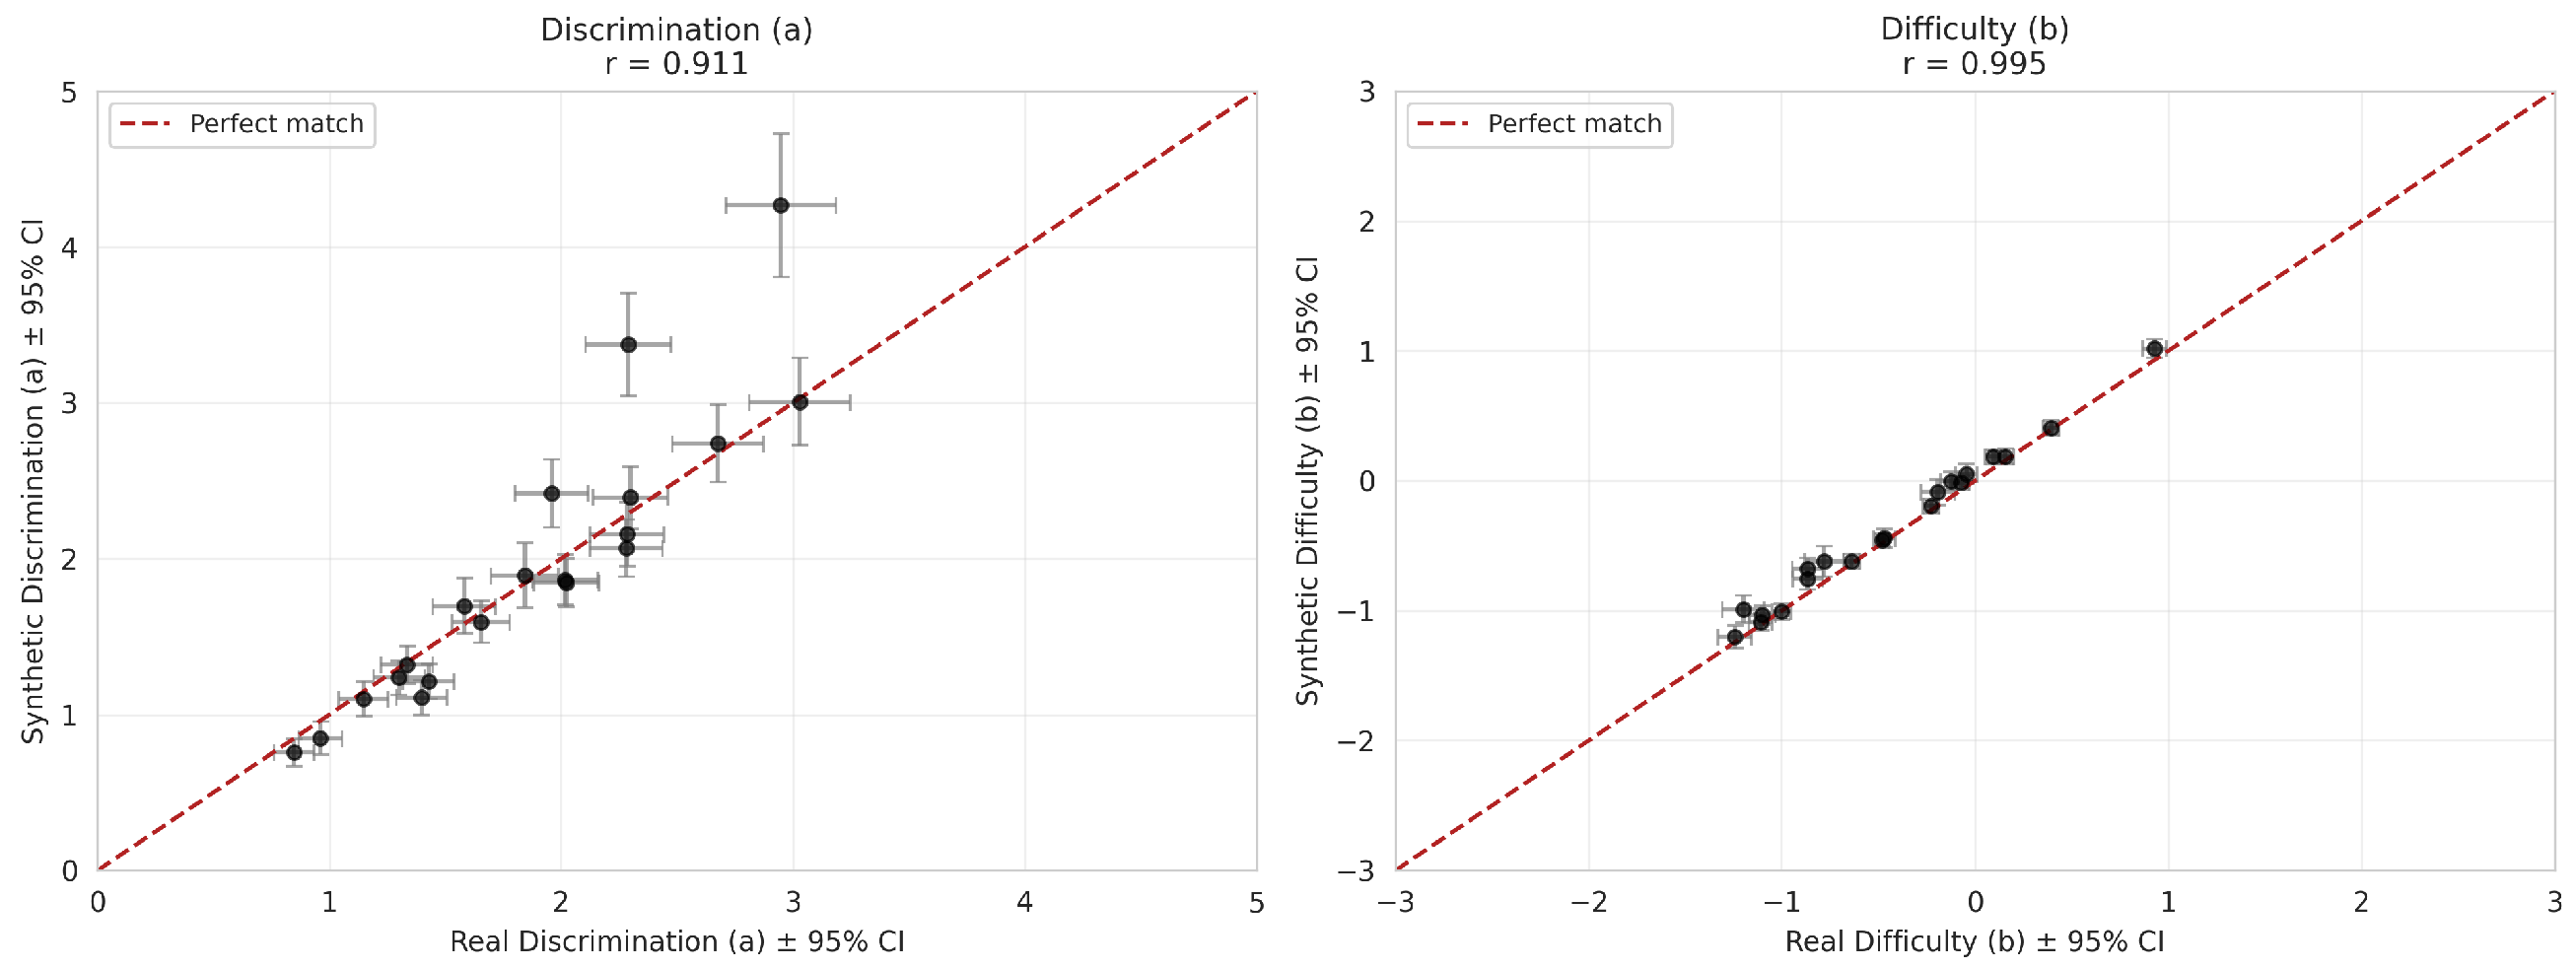
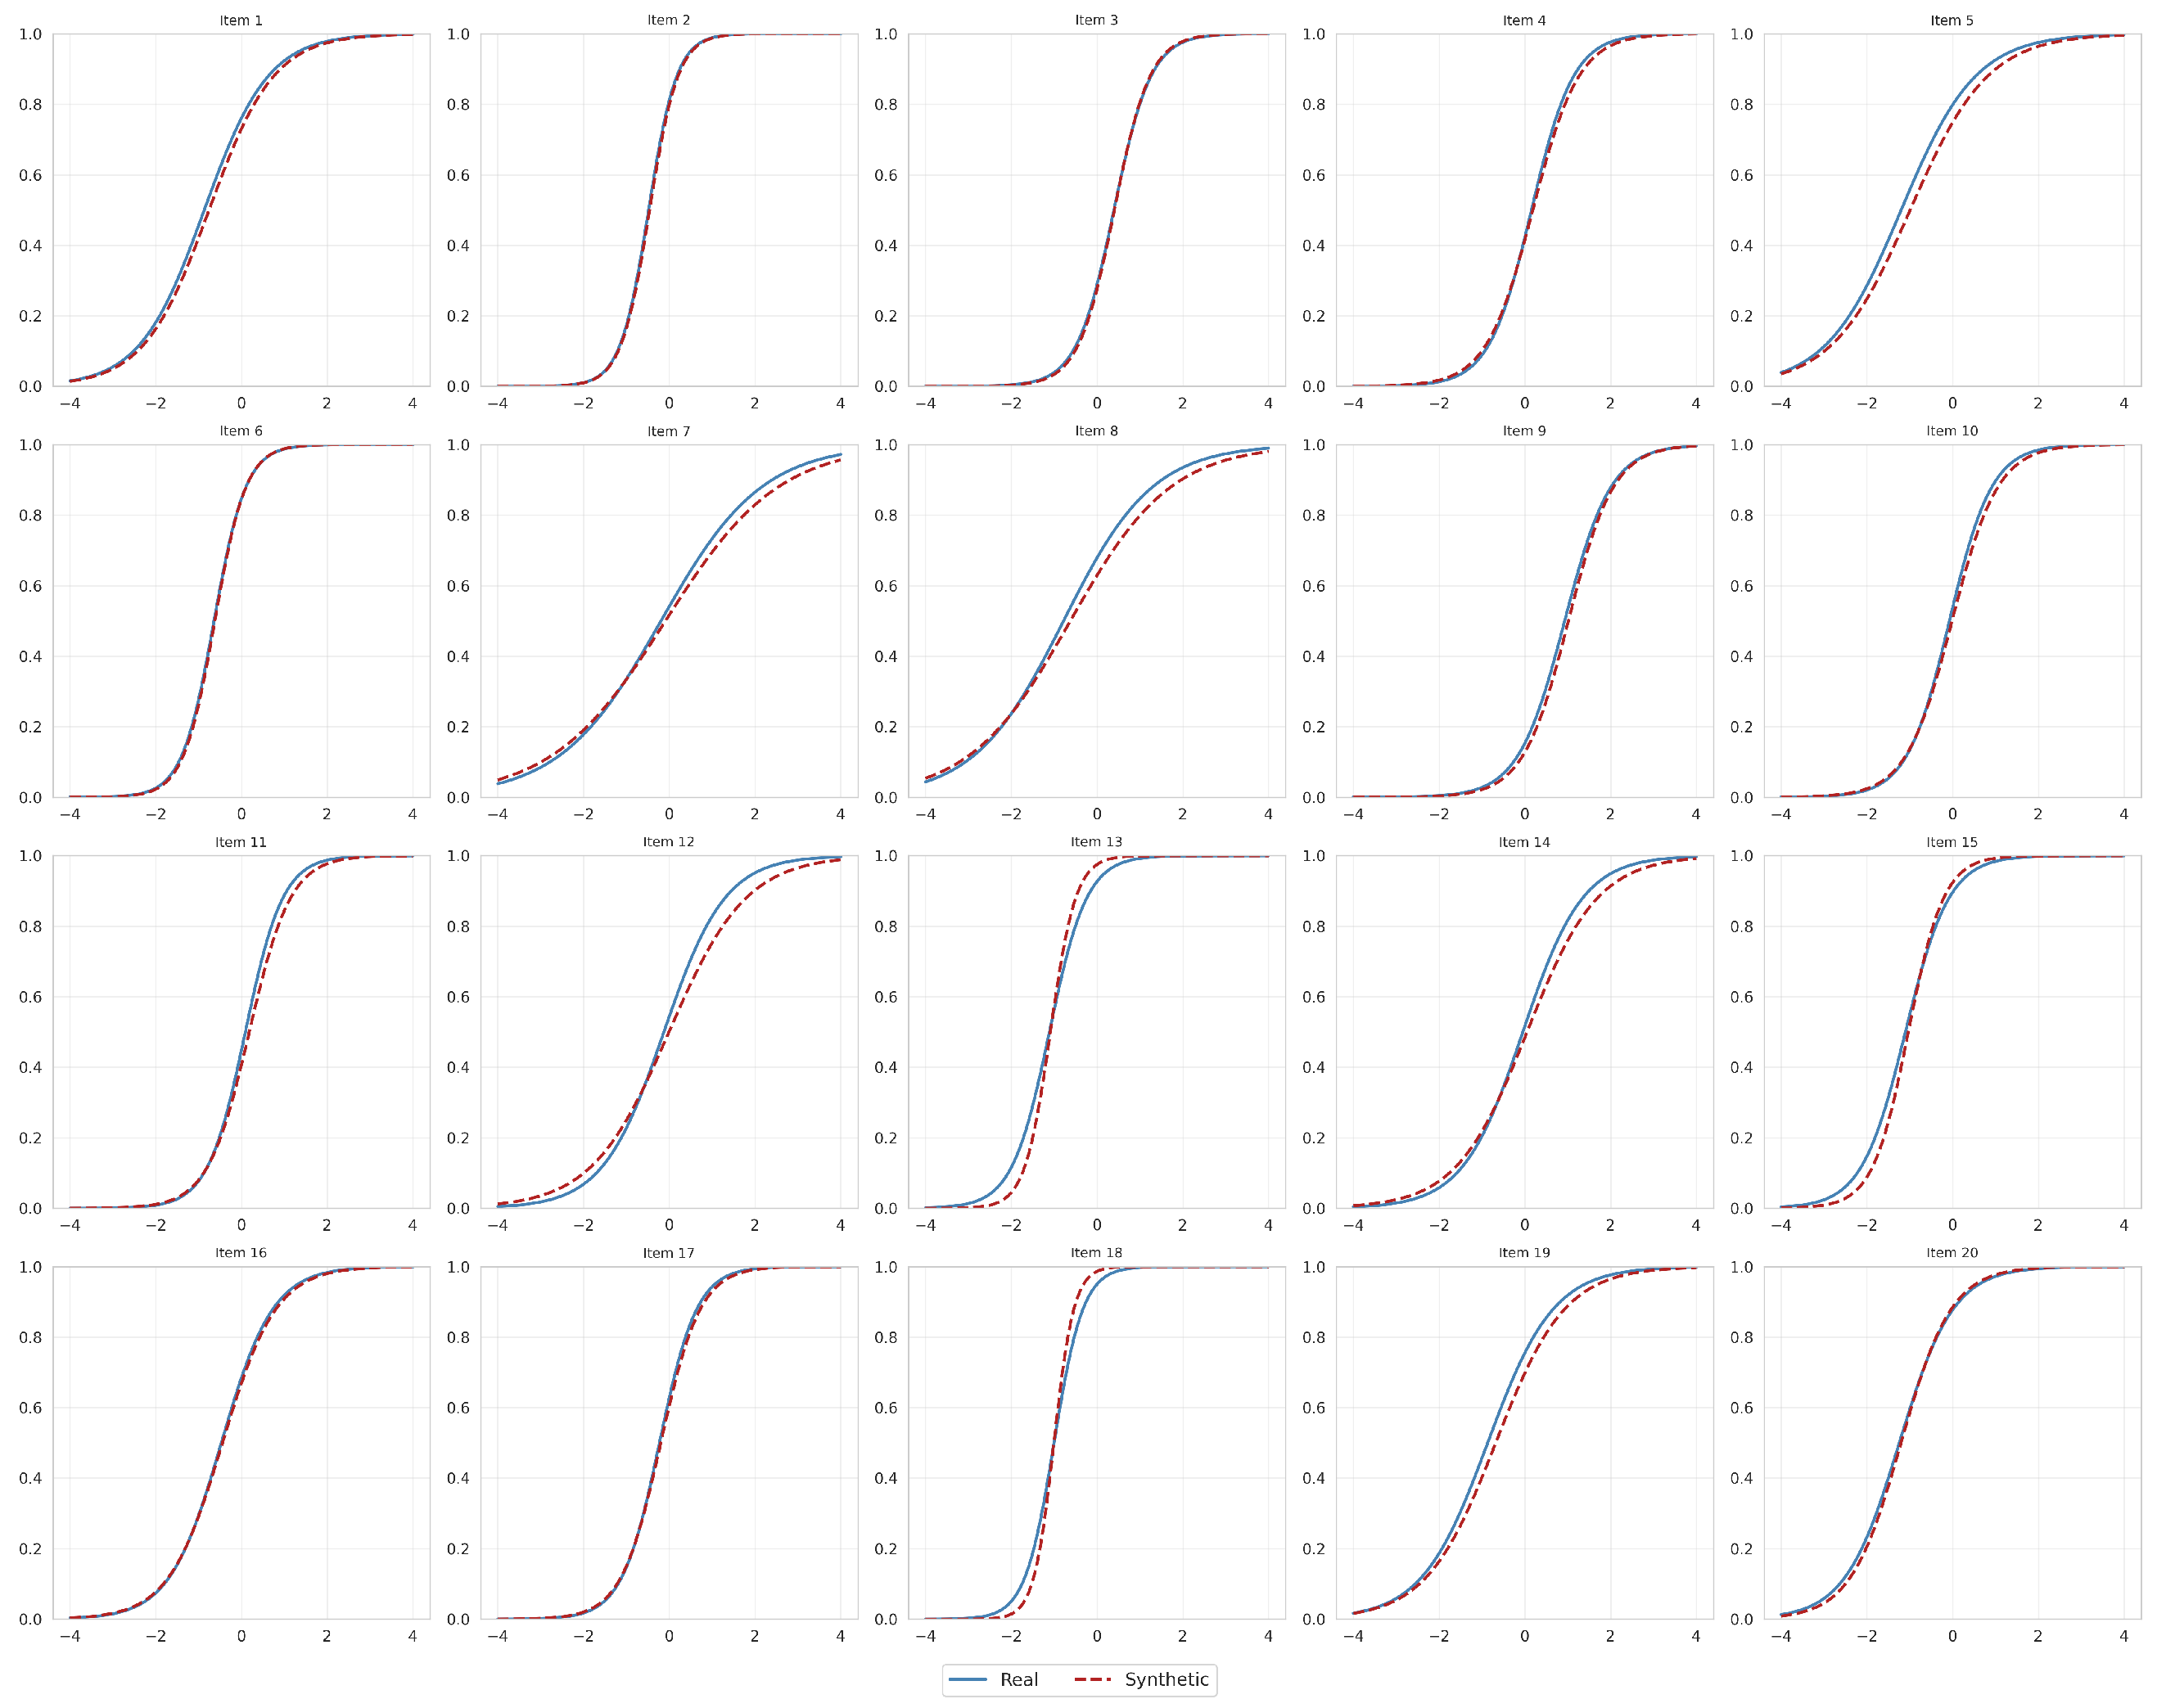
The psychometric validity of the synthetic data was evaluated by examining the consistency of IRT parameter estimates and measurement precision. As illustrated in Figure 6, the discrimination parameters (a) showed strong alignment (), although with slightly higher variability (, ), primarily driven by items with high discrimination values (e.g., Items 13 and 18), as discussed further below. The difficulty parameters (b) exhibited exceptional consistency (, , ). Despite the outliers in discrimination, the ICCs presented in Figure 7 demonstrate that the probability functions of the synthetic items closely track the empirical functions across the ability scale.
Figure 6.
Scatter plots of IRT parameters for the representative synthetic dataset versus real data. The left panel shows discrimination (a) parameters and the right panel shows difficulty (b) parameters. The red dashed line indicates a perfect match.
Figure 7.
Item Characteristic Curves (ICCs) for real (blue, solid) and synthetic (red, dashed) data across all 20 items. Each panel plots the probability of a correct response as a function of latent ability .
A notable pattern warrants specific discussion. Items 13 and 18, which possess high real discrimination values (, ), exhibited the largest positive bias in the synthetic data (, ). This amplification is systematic rather than random: the corresponding MCSEs were substantially inflated ( and 0.234, respectively, versus asymptotic estimates of 0.094 and 0.121; Table 4), and across all replications the mean synthetic discrimination for these items consistently exceeded the real values (Table 5). The ICCs for Items 13 and 18 in Figure 7 confirm that synthetic response functions remain plausible across the ability continuum, with the primary consequence being a sharp concentration of information near . This location reflects the real data: the empirical difficulty parameters (, ) indicate that the original assessment purposefully anchored highly discriminating items at this lower ability threshold to distinguish baseline proficiency.
Table 4.
Comparison of real and synthetic item parameters and standard errors.
Table 5.
Comparison of real item parameters and mean synthetic estimates across replications.
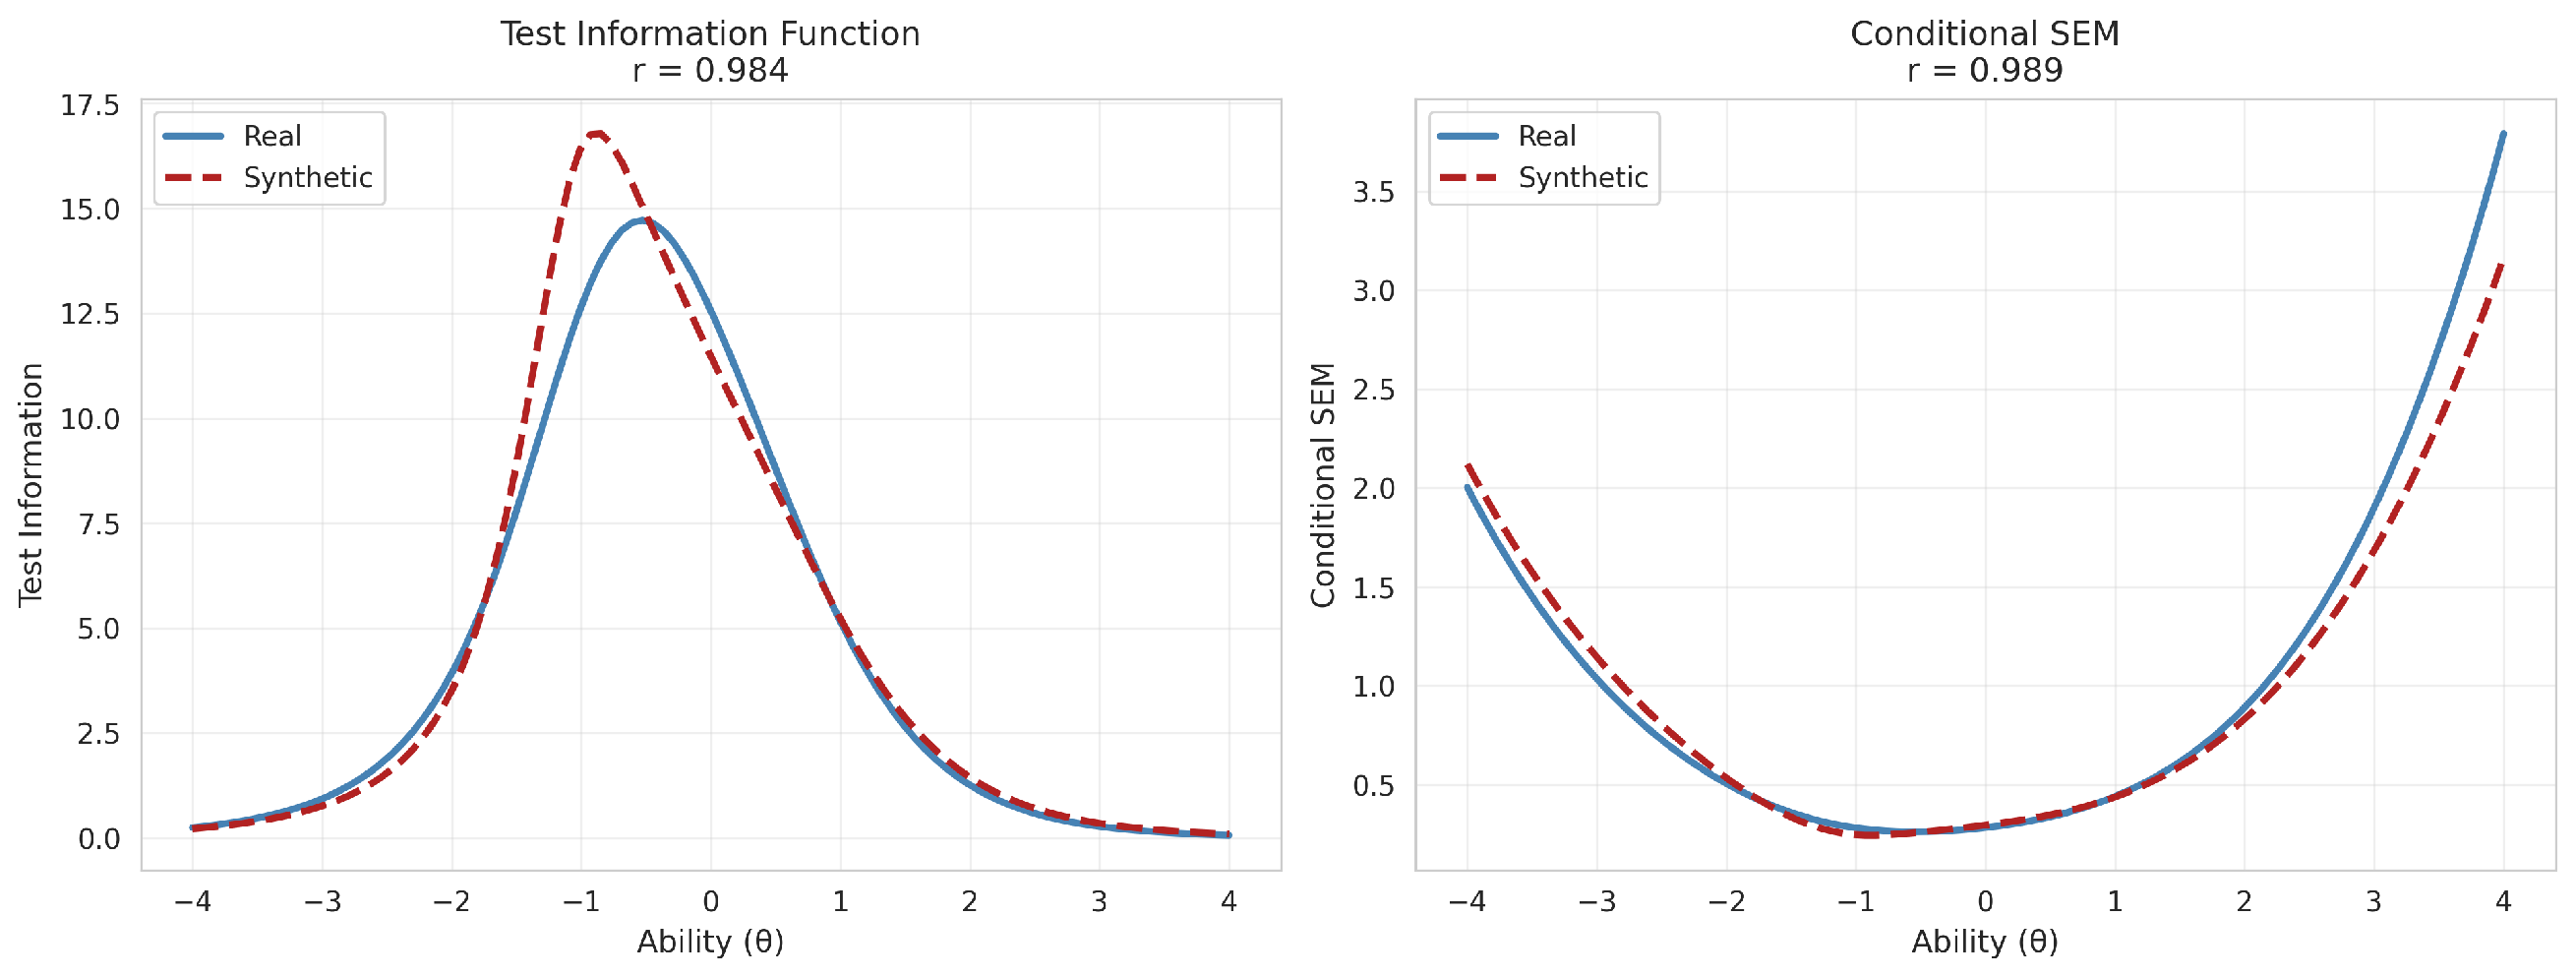
To evaluate measurement precision across the latent continuum, we examined the TIF and CSEM. As shown in Figure 8, the synthetic TIF curve follows the general trajectory of the real data, with both curves peaking in the lower ability range () and declining symmetrically toward the extremes of the scale. Although slightly higher peak information appeared around due to the high-discrimination amplification noted above, the overall profiles are highly consistent, yielding a TIF vector correlation of . The corresponding CSEM profiles mirror this pattern inversely, as measurement error is minimized precisely where information is maximized. The synthetic CSEM curve closely tracked the real curve across the full ability range, with near-identical minimum error values near and equivalent error inflation at the extremes ( and ), yielding a CSEM vector correlation of . Together, these results indicate that the synthetic data preserves the measurement precision profile of the original instrument, supporting its use in applications requiring standard error estimation across the ability continuum.
Figure 8.
Test Information Function (TIF; left panel) and Conditional Standard Errors of Measurement (CSEM; right panel) for real (blue, solid) and synthetic (red, dashed) data. Curves are evaluated over a uniform grid of 100 points, .
Systematic bias was evaluated by comparing real item parameters against the mean synthetic estimates across all replications (Table 5). For discrimination parameters (a), two opposing tendencies emerged. For the majority of items with moderate discrimination (Items 4, 11, 12, and 16), a slight attenuation bias was observed, with mean synthetic estimates under-predicting empirical values by approximately 0.069 to 0.172. This attenuation is consistent with the regularizing effect of dropout () and batch normalization in the encoder (Srivastava et al., 2014). Conversely, significant positive bias appeared for Item 18 (+1.075), Item 13 (+0.889), and Item 15 (+0.416), reflecting the KDE-induced amplification mechanism described above. For difficulty parameters (b), absolute differences were consistently low (mean absolute bias = 0.051), with the largest deviation for Item 5 (0.229).
4.3.2. Item Fit Statistics
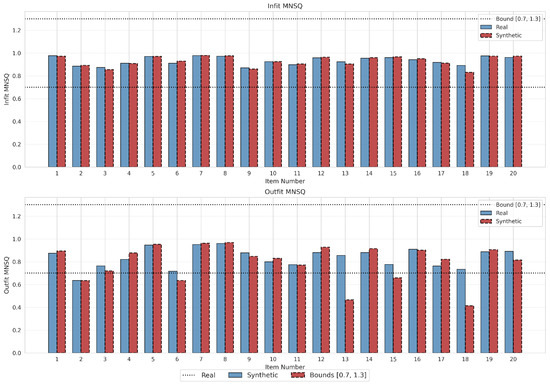
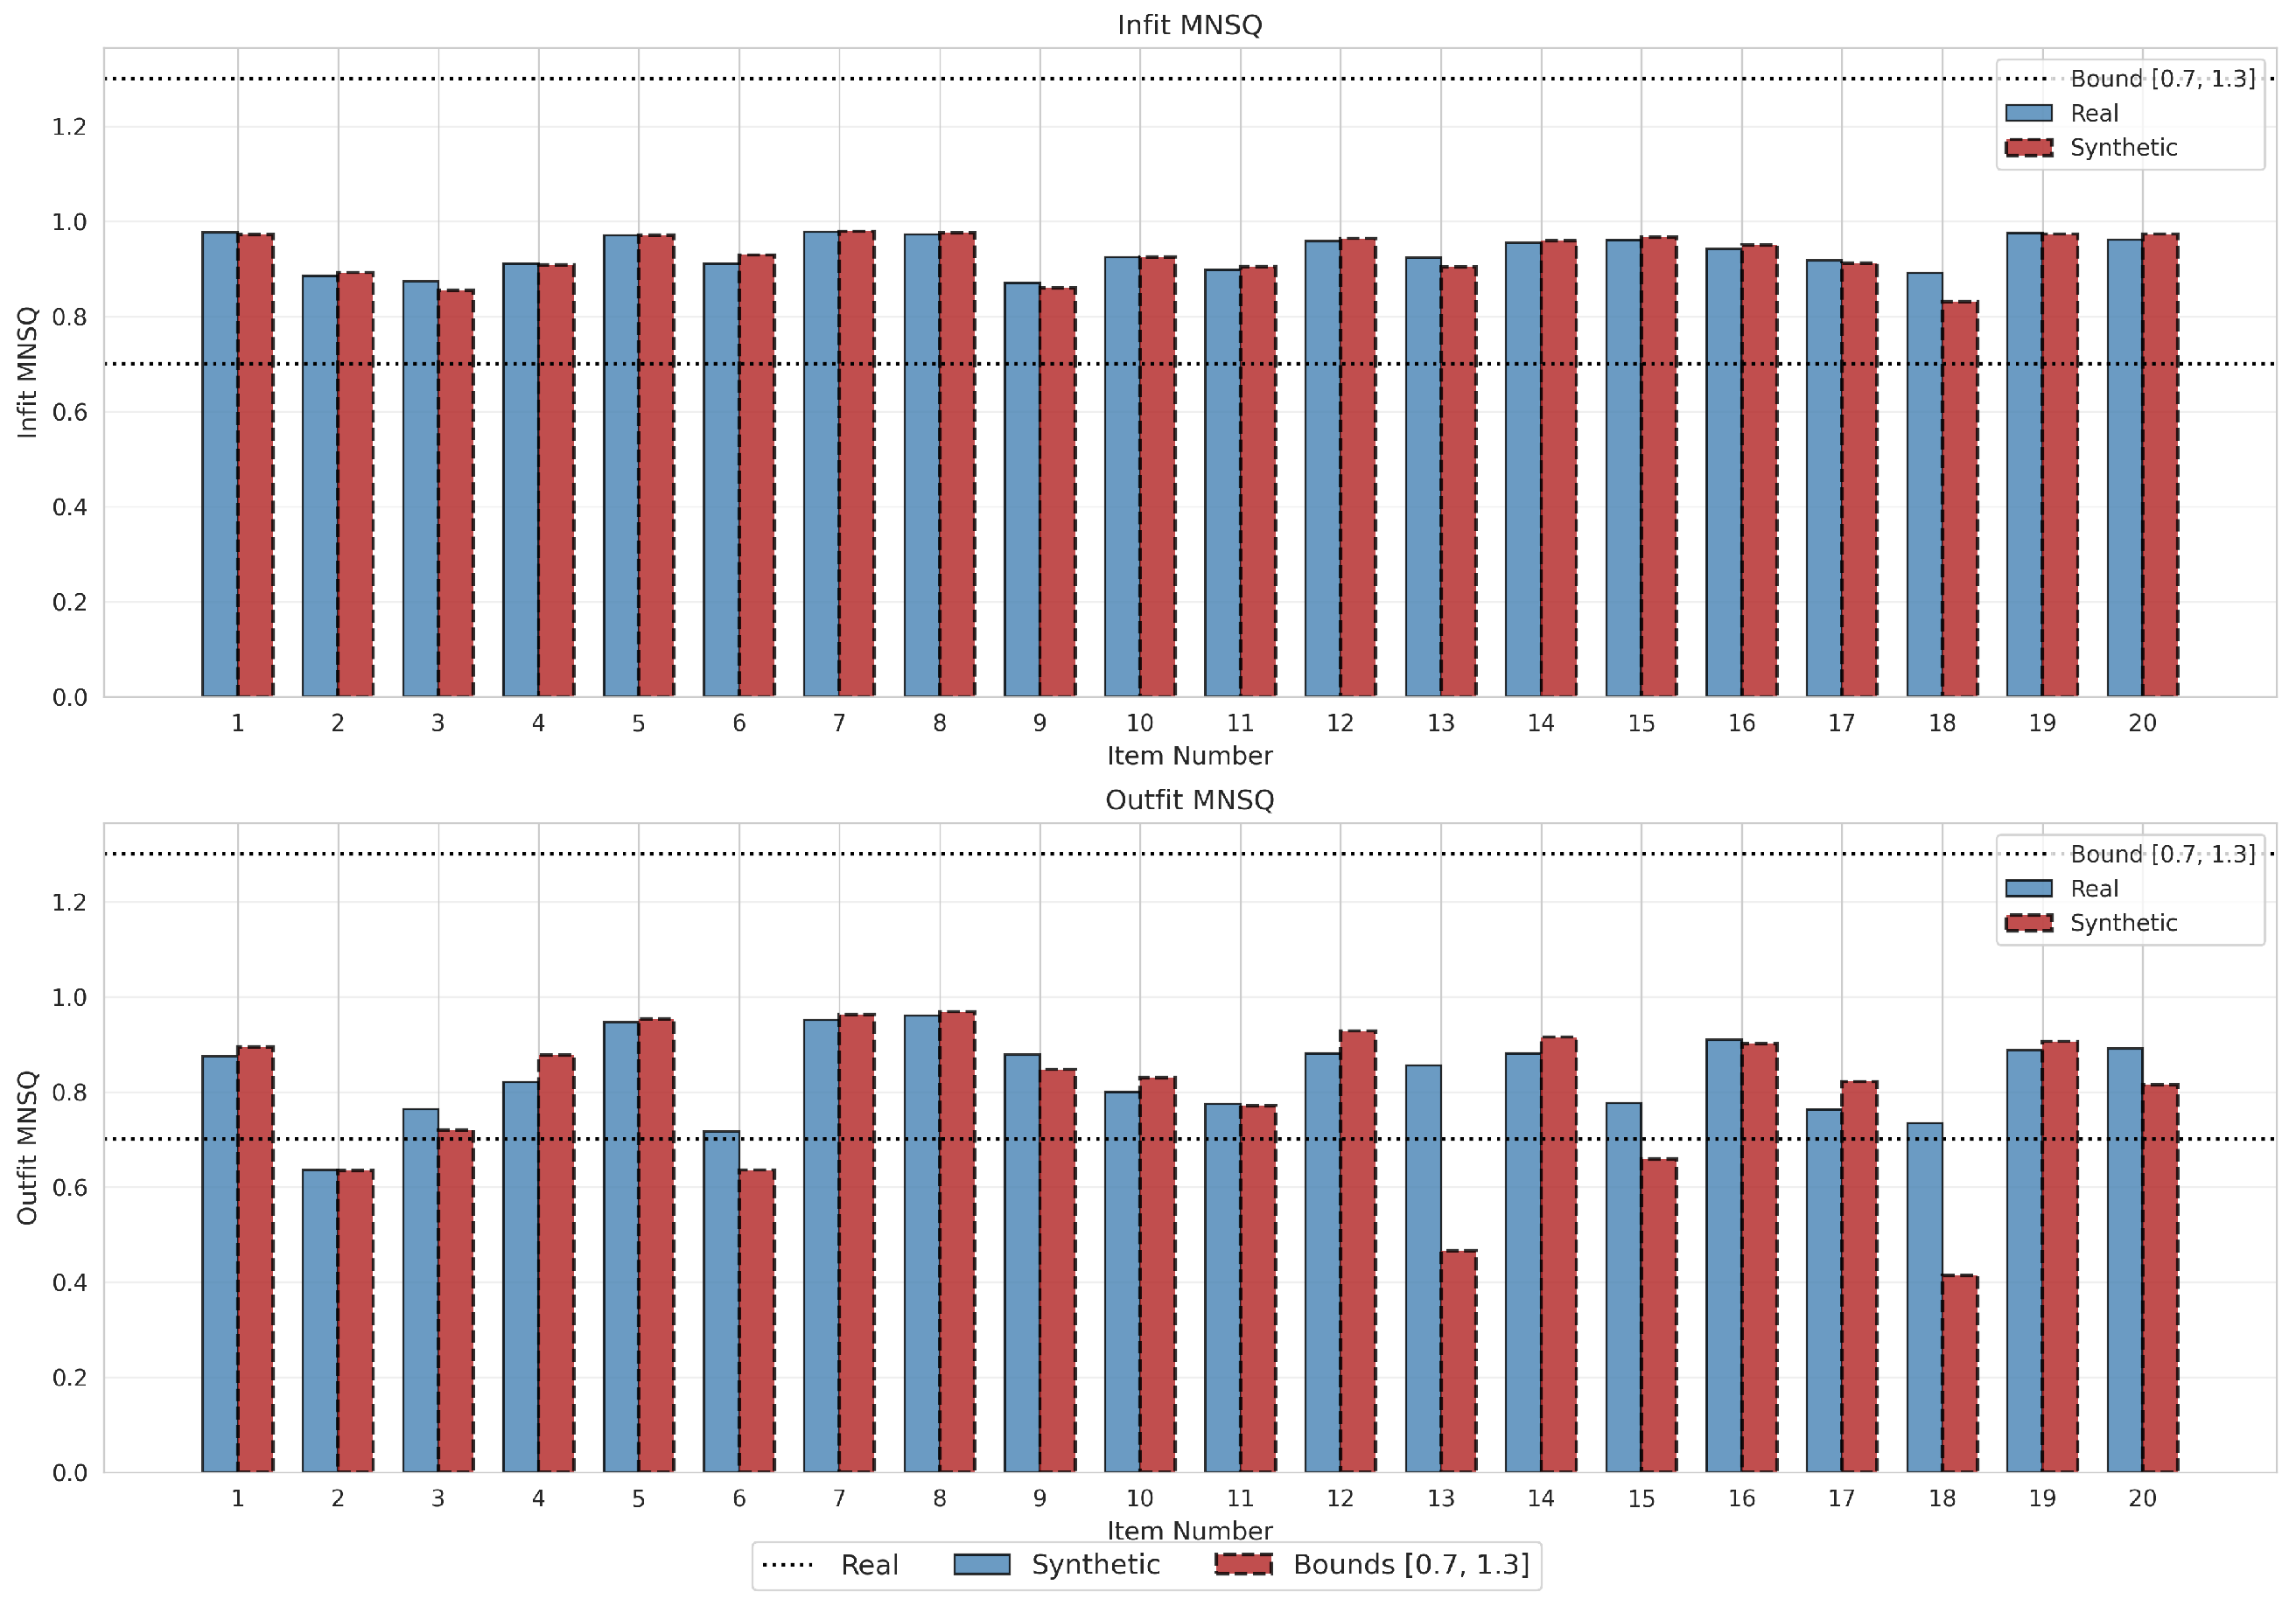
Infit statistics demonstrated remarkable stability across all 20 items, with the average absolute deviation between real and synthetic values being negligible (<0.01), and the majority of items well within the acceptable range for both datasets (Wright & Stone, 1979). Outfit statistics were largely preserved, with most items showing differences of less than 0.05. However, two items revealed localized under-dispersion: Item 13 showed a reduction from 0.856 (real) to 0.466 (synthetic), and Item 18 from 0.733 to 0.413, both falling below the 0.5 threshold for severe under-dispersion and flagged accordingly in Table 6. Item 15 showed a moderate reduction (0.776 → 0.659) but remained above the critical threshold. These patterns are consistent with the discrimination amplification mechanism described above: high-discrimination items generated response patterns that were too deterministic, suppressing the stochastic noise typically found in empirical outlier responses. Results are visualized in Figure 9.
Table 6.
Comparison of Item Infit and Outfit Mean Square statistics for real and synthetic data.
Figure 9.
Comparison of Infit (upper panel) and Outfit (lower panel) Mean Square statistics for real data (blue, solid) and synthetic data (red, dashed). Horizontal dotted lines indicate the acceptable fit range .
4.4. Inferential Precision
The synthetic data generally produced slightly larger standard errors than the real data, indicating conservative estimation of precision. On average, MCSEs exceeded ASEs for both discrimination (0.095 versus 0.074) and difficulty (0.037 versus 0.031) parameters, yielding mean MCSE/ASE ratios of 1.286 and 1.179, respectively. This conservative pattern was non-uniform across items. Items with low-to-moderate discrimination showed near-exact correspondence (e.g., Item 7: , , ratio = 1.005), while high-discrimination items exhibited substantial inflation (Item 13: ratio = 1.791; Item 18: ratio = 1.936), consistent with the amplification mechanism described in the IRT Parameter Consistency subsection above. Full item-level SE comparisons are reported in Table 4.
4.5. Stability Across Initializations
Robustness was assessed by repeating the full analysis pipeline with five distinct random seeds {101, 202, 303, 404, 505} to evaluate sensitivity to initialization and stochastic optimization paths. As summarized in Table 7, discrimination parameters (a) showed strong but slightly more variable consistency, ranging from (Seed 101) to (Seed 303), averaging 0.944 (). Difficulty parameters (b) exhibited near-perfect convergence, with correlations ranging from (Seed 505) to (Seeds 101, 303, and 404), yielding a mean of 0.995. The ranged from 0.014 (Seeds 202 and 404) to 0.019 (Seed 101), with a mean of 0.016 (). These results confirm that the NNC reliably converges to a stable structural representation of the assessment data regardless of random initialization state.
Table 7.
Stability across initializations: Results across five independent random seeds.
5. Discussion
This study introduced and validated an NNC framework for generating synthetic item response data in assessment while preserving psychometric integrity. By decoupling marginal probabilities from the dependence structure, the NNC circumvents the rigid distributional assumptions of traditional parametric IRT simulation and addresses structural gaps in existing deep generative alternatives such as GANs and VAEs, which lack explicit mechanisms for preserving marginal item properties.
5.1. Synthesis of Findings
The four-facet validation demonstrated high fidelity throughout. At the data-level, total score distributions were accurately reproduced ( versus ), marginal probabilities were well preserved (, ), and inter-item correlation structure was maintained (). This confirms that the copula encoding captured higher-order dependencies essential for dimensionality assessment in psychometric measurement. Psychometric parameter recovery was strong, with difficulty parameters showing exceptional consistency (, ) and TIF and CSEM vector correlations remaining high (, ). This indicates that the synthetic data retains sufficient measurement precision for downstream applications such as test assembly and equating. The Monte Carlo analysis () yielded slightly conservative standard error estimates (mean MCSE/ASE ratios of 1.286 for discrimination and 1.179 for difficulty), suggesting that the NNC effectively functions as a generative bootstrapping mechanism that captures model misspecification uncertainty absent from analytical ASEs (Efron & Tibshirani, 1994). Stability across initializations was confirmed across five independent retraining runs (, ; , ), demonstrating robustness to random initialization.
5.2. High-Discrimination Item Behavior
A systematic amplification of discrimination parameters was observed for the highest-discriminating items alongside attenuation for items of moderate discrimination. The attenuation reflects regularization via dropout and batch normalization, which produce a smoothed representation of the dependence structure (Ioffe & Szegedy, 2015; Srivastava et al., 2014). This shrinkage is generally benign, as Infit statistics remained stable across all items. The amplification for Items 13 and 18 (mean synthetic biases of +0.889 and +1.075 respectively across replications) is more consequential. High-discrimination items produce sharply clustered response patterns that create high-density regions in the latent space; the fixed-bandwidth KDE () over-samples these clusters, generating synthetic latent codes that decode to more deterministic response probabilities, inflating discrimination estimates and suppressing Outfit statistics below the 0.5 severe under-dispersion threshold (Wright & Stone, 1979). Adaptive bandwidth selection (Silverman, 1986) or targeted regularization tuning represent the most tractable remedies; practitioners should consider down-weighting items flagged for severe under-dispersion in discrimination-sensitive applications such as cognitive ability test assembly.
5.3. Limitations and Future Directions
Several limitations warrant consideration. First, the fixed-bandwidth KDE produced a slight underrepresentation of the maximum total score (20), consistent with known boundary bias (Jones, 1993). Boundary-corrected kernel methods or adaptive bandwidth selection would address this issue. Second, the framework is currently scoped to dichotomous responses within a unidimensional 2PL model. Extending this to polytomous formats like the Graded Response Model (Samejima, 1969) and multidimensional IRT structures (Reckase, 2009) represents a natural next step. These extensions are particularly relevant for cognitive batteries involving mixed response formats, though they introduce additional decoding complexity and heighten the curse of dimensionality in KDE (Scott, 2015). Third, transitioning to large-scale operational assessment settings introduces scalability considerations. Expanding to massive sample sizes inherently benefits deep learning models by providing the volume necessary to stabilize complex autoencoder training and accurately map the latent space. This transition requires implementing computationally efficient density estimation techniques such as normalizing flows (D. Rezende & Mohamed, 2015). Finally, using empirical data precludes evaluation against known ground-truth parameters. Future simulation studies with fixed population values would clarify the bias-variance trade-off of the NNC estimator relative to standard MML approaches.
6. Conclusions
This study demonstrated that the NNC framework offers a robust and data-driven alternative to traditional parametric simulation and existing deep generative models for synthetic item response data generation. The four-facet validation confirmed high fidelity across data-level consistency, psychometric parameter recovery, test information preservation, and inferential precision. Furthermore, the MCSE/ASE ratios establish the NNC as a principled generative bootstrapping mechanism. The primary limitation identified was the amplification of discrimination for highly discriminating items. This artifact is attributable to the fixed-bandwidth KDE and represents a tractable target for future refinement that does not undermine the overall validity of the framework. As the volume and complexity of educational and psychological assessment data continue to expand, flexible generative architectures of this kind will prove increasingly vital for securely sharing data, enabling reproducible research, and benchmarking emerging psychometric methodologies.
Author Contributions
Conceptualization, J.J., M.L. and W.-C.L.; methodology, J.J. and M.L.; formal analysis, J.J.; data curation, W.-C.L.; writing—original draft preparation, J.J.; writing—review and editing, M.L. and W.-C.L.; supervision, W.-C.L. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The complete implementation code and a sampled dataset (provided due to privacy protocols) for public replication are openly available at https://github.com/Ju-youngJung/Neural-Network-Copula-Synthetic-Data.git (accessed on 14 April 2026).
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| 2PL | Two-Parameter Logistic |
| ASE | Asymptotic Standard Error |
| CSEM | Conditional Standard Error of Measurement |
| EAP | Expected A Posteriori |
| EM | Expectation-Maximization |
| GAN | Generative Adversarial Network |
| ICC | Item Characteristic Curve |
| IRT | Item Response Theory |
| KDE | Kernel Density Estimation |
| MAD | Mean Absolute Deviation |
| MCSE | Monte Carlo Standard Error |
| MML | Marginal Maximum Likelihood |
| NNC | Neural Network Copula |
| ReLU | Rectified Linear Unit |
| TIF | Test Information Function |
| VAE | Variational Autoencoder |
Appendix A. Neural Network Copula Algorithms
The following pseudocode details the complete pipeline for the NNC framework. Algorithm A1 outlines the model training procedure, including the transformation of binary responses to pseudo-uniform marginals and the optimization of the deep autoencoder. Algorithm A2 describes the synthetic data generation process, which utilizes KDE to sample from the learned latent space and the inverse probability integral transform to produce binary responses.
| Algorithm A1 Neural Network Copula Training Procedure |
| Require: Training data ( binary matrix), Validation data () Require: Configuration Ensure: Trained , marginal probabilities , training history
|
| Algorithm A2 Synthetic Data Generation via Neural Network Copula |
| Require: Trained , training pseudo-uniform matrix , marginal probabilities , number of synthetic samples , random seed s Ensure: Synthetic binary response matrix
|
References
- Arjovsky, M., Chintala, S., & Bottou, L. (2017). Wasserstein generative adversarial networks. In Proceedings of the 34th international conference on machine learning (pp. 214–223). PMLR. [Google Scholar]
- Baker, F. B., & Kim, S.-H. (2004). Item response theory: Parameter estimation techniques (2nd ed.). CRC Press. [Google Scholar]
- Bartholomew, D. J. (1980). Factor analysis for categorical data. Journal of the Royal Statistical Society: Series B, 42(3), 293–312. [Google Scholar] [CrossRef] [Scilit]
- Birnbaum, A. (1968). Some latent trait models and their use in inferring an examinee’s ability. In F. M. Lord, & M. R. Novick (Eds.), Statistical theories of mental test scores (pp. 397–479). Addison-Wesley. [Google Scholar]
- Bock, R. D., & Aitkin, M. (1981). Marginal maximum likelihood estimation of item parameters: Application of an EM algorithm. Psychometrika, 46(4), 443–459. [Google Scholar] [CrossRef] [Scilit]
- Bock, R. D., & Mislevy, R. J. (1982). Adaptive EAP estimation of ability in a microcomputer environment. Applied Psychological Measurement, 6(4), 431–444. [Google Scholar] [CrossRef] [Scilit]
- Bowman, S., Vilnis, L., Vinyals, O., Dai, A., Jozefowicz, R., & Bengio, S. (2016). Generating sentences from a continuous space. In Proceedings of the 20th SIGNLL conference on computational natural language learning (pp. 10–21). Association for Computational Linguistics. [Google Scholar]
- Braeken, J., Tuerlinckx, F., & De Boeck, P. (2007). Copula functions for residual dependency. Psychometrika, 72(3), 393–411. [Google Scholar] [CrossRef] [Scilit]
- Chalmers, R. P. (2016). Generating adaptive and non-adaptive test interfaces for multidimensional item response theory applications. Journal of Statistical Software, 71(5), 1–38. [Google Scholar] [CrossRef] [Scilit]
- Chen, W.-H., & Thissen, D. (1997). Local dependence indexes for item pairs using item response theory. Journal of Educational and Behavioral Statistics, 22(3), 265–289. [Google Scholar] [CrossRef] [Scilit]
- Choi, E., Biswal, S., Malin, B., Duke, J., Stewart, W. F., & Sun, J. (2017). Generating multi-label discrete patient records using generative adversarial networks. In Proceedings of machine learning for healthcare conference (pp. 286–305). PMLR. [Google Scholar]
- Drechsler, J. (2011). Synthetic datasets for statistical disclosure control: Theory and implementation (Vol. 201). Springer Science & Business Media. [Google Scholar]
- Drechsler, J., & Reiter, J. P. (2011). An empirical evaluation of easily implemented, nonparametric methods for generating synthetic datasets. Computational Statistics & Data Analysis, 55(12), 3232–3243. [Google Scholar] [CrossRef] [Scilit]
- Efron, B., & Tibshirani, R. J. (1994). An introduction to the bootstrap. Chapman & Hall/CRC. [Google Scholar]
- Embretson, S. E., & Yang, X. (2012). Item response theory. In J. L. Green, G. Camilli, & P. B. Elmore (Eds.), Handbook of complementary methods in education research (3rd ed., pp. 385–410). Routledge. [Google Scholar]
- Formann, A. K. (2007). Mixture analysis of multivariate categorical data with covariates and missing entries. Computational Statistics & Data Analysis, 51(11), 5236–5246. [Google Scholar] [CrossRef] [Scilit]
- Fox, J.-P., & Marianti, S. (2016). Joint modeling of ability and differential speed using responses and response times. Multivariate Behavioral Research, 51(4), 540–553. [Google Scholar] [CrossRef] [Scilit]
- Genest, C., Rémillard, B., & Beaudoin, D. (2009). Goodness-of-fit tests for copulas: A review and a power study. Insurance: Mathematics and Economics, 44(2), 199–213. [Google Scholar] [CrossRef] [Scilit]
- Glorot, X., Bordes, A., & Bengio, Y. (2011). Deep sparse rectifier neural networks. In Proceedings of the 14th international conference on artificial intelligence and statistics (pp. 315–323). PMLR. [Google Scholar]
- Goodfellow, I., Bengio, Y., & Courville, A. (2016). Deep learning. MIT Press. [Google Scholar]
- Goodfellow, I. J., Pouget-Abadie, J., Mirza, M., Xu, B., Warde-Farley, D., Ozair, S., Courville, A., & Bengio, Y. (2014). Generative adversarial nets. In Advances in neural information processing systems (pp. 2672–2680). MIT Press. [Google Scholar]
- Hambleton, R. K., Swaminathan, H., & Rogers, H. J. (1991). Fundamentals of item response theory (Vol. 2). Sage. [Google Scholar]
- Harwell, M. R. (1997). Analyzing the results of Monte Carlo studies in item response theory. Educational and Psychological Measurement, 57(2), 266–279. [Google Scholar] [CrossRef] [Scilit]
- Hinton, G. E., & Salakhutdinov, R. R. (2006). Reducing the dimensionality of data with neural networks. Science, 313(5786), 504–507. [Google Scholar] [CrossRef] [Scilit]
- Hu, L., & Bentler, P. M. (1999). Cutoff criteria for fit indexes in covariance structure analysis: Conventional criteria versus new alternatives. Structural Equation Modeling, 6(1), 1–55. [Google Scholar] [CrossRef] [Scilit]
- Ioffe, S., & Szegedy, C. (2015). Batch normalization: Accelerating deep network training by reducing internal covariate shift. In Proceedings of the 32nd international conference on machine learning (pp. 448–456). PMLR. [Google Scholar]
- Joe, H. (2014). Dependence modeling with copulas. CRC Press. [Google Scholar]
- Jones, M. C. (1993). Simple boundary correction for kernel density estimation. Statistics and Computing, 3(3), 135–146. [Google Scholar] [CrossRef] [Scilit]
- Junker, B. W., & Sijtsma, K. (2001). Cognitive assessment models with few assumptions, and connections with nonparametric item response theory. Applied Psychological Measurement, 25(3), 258–272. [Google Scholar] [CrossRef] [Scilit]
- Kadhem, S. H., & Nikoloulopoulos, A. K. (2023a). Bi-factor and second-order copula models for item response data. Psychometrika, 88(1), 132–157. [Google Scholar] [CrossRef] [Scilit]
- Kadhem, S. H., & Nikoloulopoulos, A. K. (2023b). Factor tree copula models for item response data. Psychometrika, 88(3), 776–802. [Google Scholar] [CrossRef] [Scilit]
- Kingma, D. P., & Ba, J. (2014). Adam: A method for stochastic optimization. arXiv, arXiv:1412.6980. [Google Scholar]
- Kingma, D. P., & Welling, M. (2014). Auto-encoding variational Bayes. arXiv, arXiv:1312.6114. [Google Scholar]
- Koehler, E., Brown, E., & Haneuse, S. J.-P. A. (2009). On the assessment of Monte Carlo error in simulation-based statistical analyses. The American Statistician, 63(2), 155–162. [Google Scholar] [CrossRef] [Scilit]
- LeCun, Y., Bengio, Y., & Hinton, G. (2015). Deep learning. Nature, 521(7553), 436–444. [Google Scholar] [CrossRef] [Scilit]
- Letizia, N. A., Novello, N., & Tonello, A. M. (2025). Copula density neural estimation. IEEE Transactions on Neural Networks and Learning Systems, 36(10), 19452–19459. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Lord, F. M., Novick, M. R., & Birnbaum, A. (1968). Statistical theories of mental test scores. Addison-Wesley. [Google Scholar]
- Mendes, B. V., de Melo, E. F., & Nelsen, R. B. (2007). Robust fits for copula models. Communications in Statistics—Simulation and Computation, 36(5), 997–1017. [Google Scholar] [CrossRef] [Scilit]
- Nelsen, R. B. (2006). An introduction to copulas (2nd ed.). Springer. [Google Scholar]
- Nikoloulopoulos, A. K., & Joe, H. (2015). Factor copula models for item response data. Psychometrika, 80(1), 126–150. [Google Scholar] [CrossRef] [Scilit]
- Paszke, A., Gross, S., Massa, F., Lerer, A., Bradbury, J., Chanan, G., Killeen, T., Lin, Z., Gimelshein, N., Antiga, L., Desmaison, A., Köpf, A., Yang, E., DeVito, Z., Raison, M., Tejani, A., Chilamkurthy, S., Steiner, B., Fang, L., … Chintala, S. (2019). PyTorch an imperative style, high-performance deep learning library. arXiv, arXiv:1912.01703. [Google Scholar]
- Prechelt, L. (1998). Automatic early stopping using cross validation: Quantifying the criteria. Neural Networks, 11(4), 761–767. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Raab, G. M., Nowok, B., & Dibben, C. (2016). Practical data synthesis for large samples. Journal of Privacy and Confidentiality, 7(3), 67–97. [Google Scholar] [CrossRef] [Scilit]
- Raghunathan, T. E., Reiter, J. P., & Rubin, D. B. (2003). Multiple imputation for statistical disclosure limitation. Journal of Official Statistics, 19(1), 1–16. [Google Scholar]
- Reckase, M. D. (1985). The difficulty of test items that measure more than one ability. Applied Psychological Measurement, 9(4), 401–412. [Google Scholar] [CrossRef] [Scilit]
- Reckase, M. D. (2009). Multidimensional item response theory. Springer. [Google Scholar]
- Reiter, J. P. (2005). Releasing multiply imputed, synthetic public use microdata: An illustration and empirical study. Journal of the Royal Statistical Society Series A: Statistics in Society, 168(1), 185–205. [Google Scholar] [CrossRef] [Scilit]
- Rezende, D., & Mohamed, S. (2015). Variational inference with normalizing flows. In International conference on machine learning (pp. 1530–1538). PMLR. [Google Scholar]
- Rezende, D. J., Mohamed, S., & Wierstra, D. (2014). Stochastic backpropagation and approximate inference in deep generative models. In International conference on machine learning (pp. 1278–1286). PMLR. [Google Scholar]
- Robert, C. P., & Casella, G. (2004). Monte Carlo statistical methods (2nd ed.). Springer. [Google Scholar]
- Rubin, D. B. (1993). Discussion: Statistical disclosure limitation. Journal of Official Statistics, 9(2), 461–468. [Google Scholar]
- Rubin, D. B. (2018). Multiple imputation. In S. van Buuren (Ed.), Flexible imputation of missing data (2nd ed., pp. 29–62). Chapman & Hall/CRC. [Google Scholar]
- Rüschendorf, L. (2009). On the distributional transform, Sklar’s theorem, and the empirical copula process. Journal of Statistical Planning and Inference, 139(11), 3921–3927. [Google Scholar] [CrossRef] [Scilit]
- Salimans, T., Goodfellow, I., Zaremba, W., Cheung, V., Radford, A., & Chen, X. (2016). Improved techniques for training GANs. In D. Lee, M. Sugiyama, U. Luxburg, I. Guyon, & R. Garnett (Eds.), Advances in neural information processing systems (Vol. 29). Curran Associates, Inc. [Google Scholar]
- Samejima, F. (1969). Estimation of latent ability using a response pattern of graded scores. Psychometrika Monograph Supplement, 34(4), 100. [Google Scholar] [CrossRef] [Scilit]
- Sanchez, R. (2021). GIRTH G. Item response theory (Version 0.8.0) [Computer software]. Available online: https://github.com/eribean/girth (accessed on 3 January 2026).
- Schmidt, R., & Stadtmüller, U. (2006). Non-parametric estimation of tail dependence. Scandinavian Journal of Statistics, 33(2), 307–335. [Google Scholar] [CrossRef] [Scilit]
- Scott, D. W. (2015). Multivariate density estimation: Theory, practice, and visualization. Wiley. [Google Scholar]
- Si, Y., & Reiter, J. P. (2013). Nonparametric Bayesian multiple imputation for incomplete categorical variables in large-scale assessment surveys. Journal of Educational and Behavioral Statistics, 38(5), 499–521. [Google Scholar] [CrossRef] [Scilit]
- Sijtsma, K., & Molenaar, I. W. (2002). Introduction to nonparametric item response theory (Vol. 5). Sage. [Google Scholar]
- Silverman, B. W. (1986). Density estimation for statistics and data analysis. Routledge. [Google Scholar]
- Sklar, A. (1959). Fonctions de répartition à n dimensions et leurs marges. Publications de l’Institut de Statistique de l’Université de Paris, 8(3), 229–231. [Google Scholar]
- Srivastava, N., Hinton, G., Krizhevsky, A., Sutskever, I., & Salakhutdinov, R. (2014). Dropout: A simple way to prevent neural networks from overfitting. Journal of Machine Learning Research, 15(1), 1929–1958. [Google Scholar]
- Stout, W. (1987). A nonparametric approach for assessing latent trait unidimensionality. Psychometrika, 52(4), 589–617. [Google Scholar] [CrossRef] [Scilit]
- Thissen, D., Nelson, L., Rosa, K., & McLeod, L. D. (2001). Item response theory for items scored in more than two categories. In D. Thissen, & H. Wainer (Eds.), Test scoring (pp. 153–198). Routledge. [Google Scholar]
- Thissen, D., Pommerich, M., Billeaud, K., & Williams, V. S. L. (1995). Item response theory for scores on tests including polytomous items with ordered responses. Applied Psychological Measurement, 19(1), 39–49. [Google Scholar] [CrossRef] [Scilit]
- Vermunt, J. K. (2004). Latent profile model. In M. S. Lewis-Beck, A. Bryman, & T. F. Liao (Eds.), The SAGE encyclopedia of social science research methods (pp. 554–555). Sage. [Google Scholar]
- Wang, C., & Nydick, S. W. (2015). Comparing two algorithms for calibrating the restricted non-compensatory multidimensional IRT model. Applied Psychological Measurement, 39(2), 119–134. [Google Scholar] [CrossRef] [Scilit]
- Wright, B. D., & Stone, M. H. (1979). Best test design. Mesa Press. [Google Scholar]
- Xu, L., Skoularidou, M., Cuesta-Infante, A., & Veeramachaneni, K. (2019). Modeling tabular data using conditional GAN. Advances in Neural Information Processing Systems, 32, 7335–7345. [Google Scholar]
- Yang, R.-S., Sun, L.-J., Li, H.-B., & Yang, Y. (2024). A neural network copula function approach for solving joint basic probability assignment in structural reliability analysis. Quality and Reliability Engineering International, 40(6), 3096–3119. [Google Scholar] [CrossRef] [Scilit]
- Yang, Y., & Xia, Y. (2015). On the number of factors to retain in exploratory factor analysis for ordered categorical data. Behavior Research Methods, 47(3), 756–772. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Yen, W. M. (1984). Effects of local item dependence on the fit and equating performance of the three-parameter logistic model. Applied Psychological Measurement, 8(2), 125–145. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.