Article

Fully Cross-Attention Transformer for Guided Depth Super-Resolution

Andrew and Erna Viterbi Faculty of Electrical and Computer Engineering, Technion—Israel Institute of Technology, Haifa 3200003, Israel
*
Authors to whom correspondence should be addressed.
Sensors 2023, 23(5), 2723; https://doi.org/10.3390/s23052723
Submission received: 16 February 2023 / Revised: 26 February 2023 / Accepted: 27 February 2023 / Published: 2 March 2023
(This article belongs to the Special Issue Deep Learning Technology and Image Sensing)

Abstract

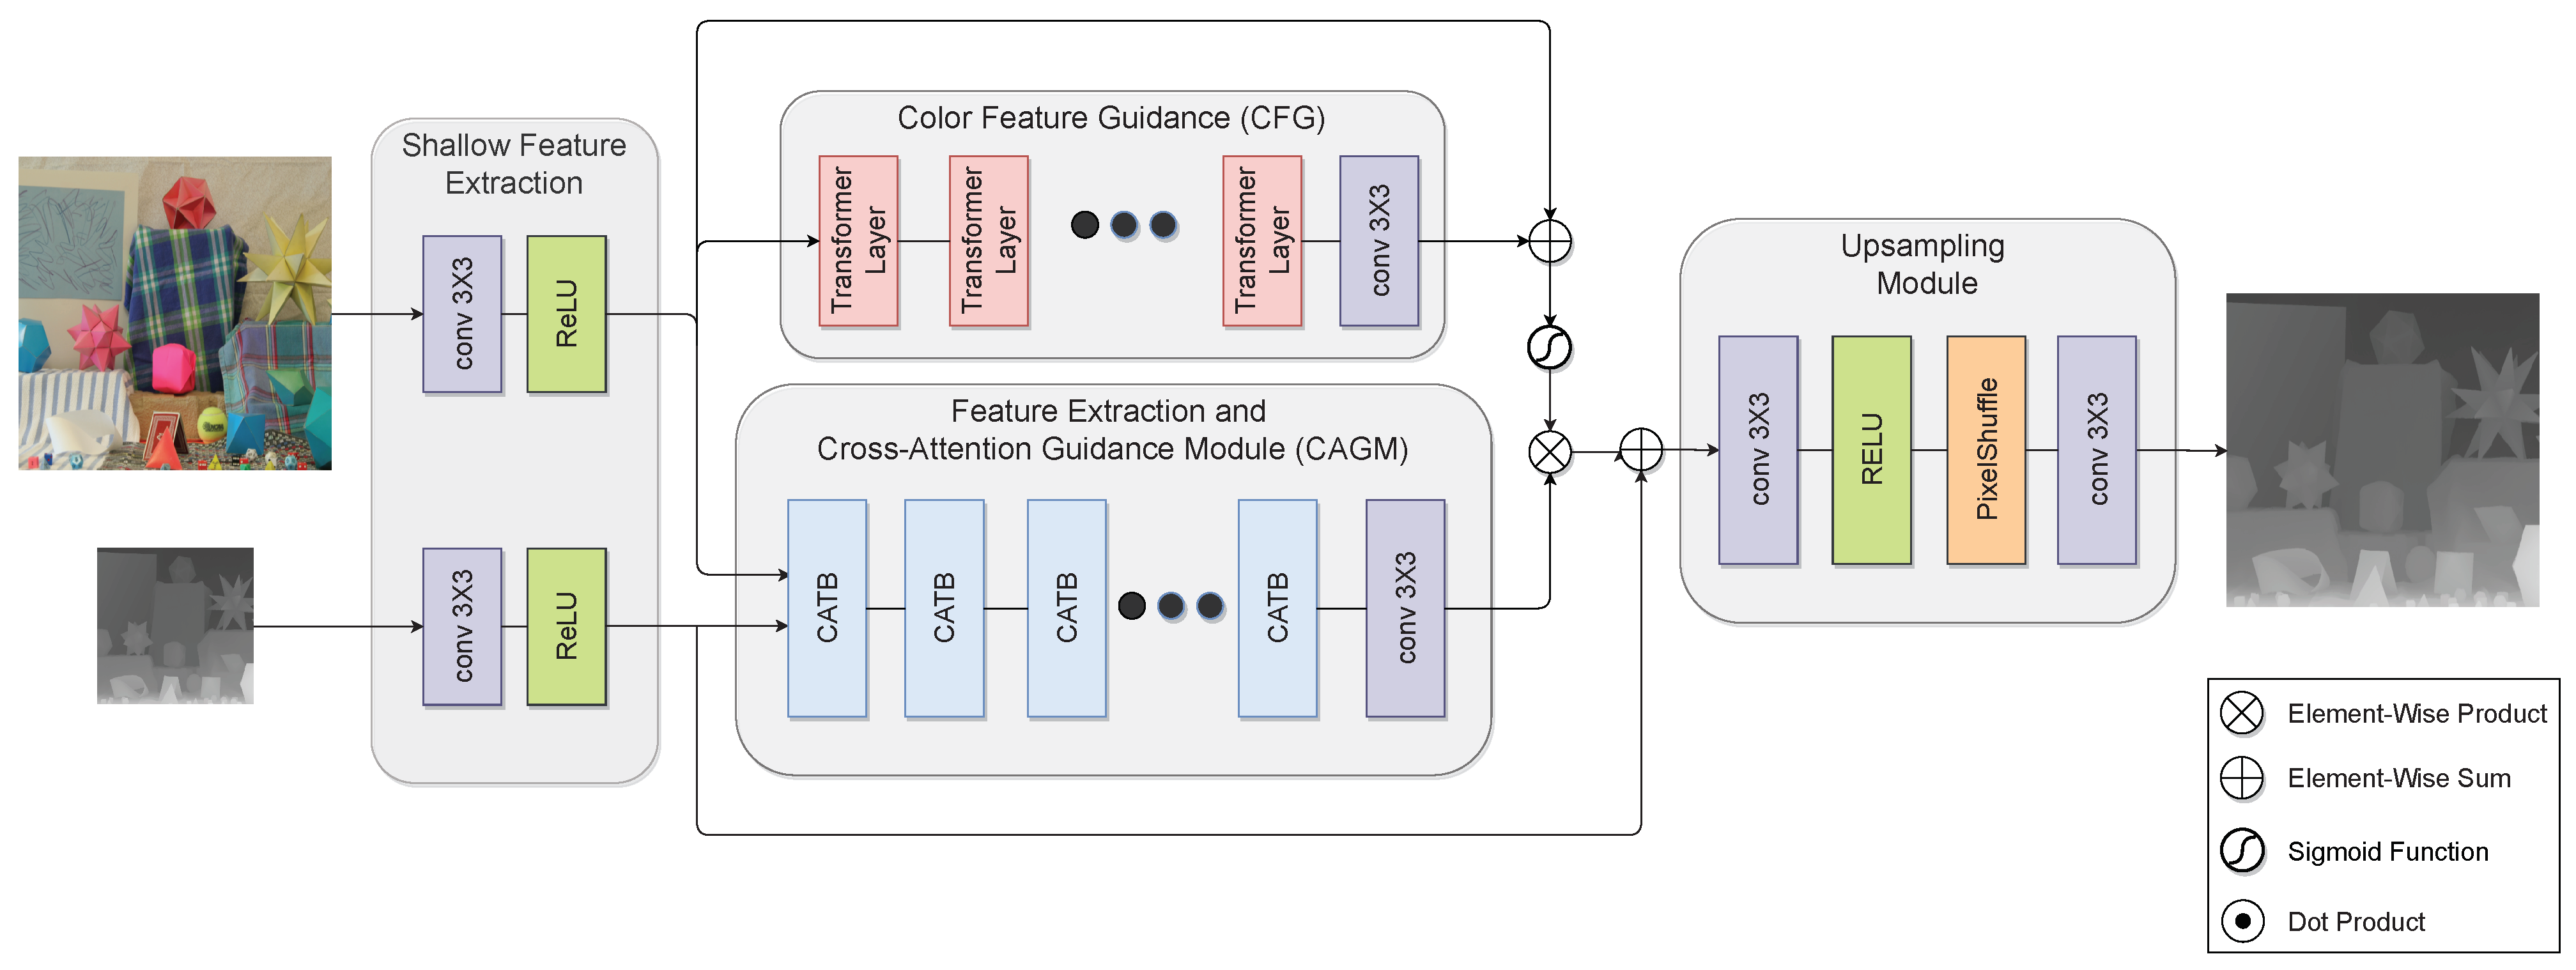
Modern depth sensors are often characterized by low spatial resolution, which hinders their use in real-world applications. However, the depth map in many scenarios is accompanied by a corresponding high-resolution color image. In light of this, learning-based methods have been extensively used for guided super-resolution of depth maps. A guided super-resolution scheme uses a corresponding high-resolution color image to infer high-resolution depth maps from low-resolution ones. Unfortunately, these methods still have texture copying problems due to improper guidance from color images. Specifically, in most existing methods, guidance from the color image is achieved by a naive concatenation of color and depth features. In this paper, we propose a fully transformer-based network for depth map super-resolution. A cascaded transformer module extracts deep features from a low-resolution depth. It incorporates a novel cross-attention mechanism to seamlessly and continuously guide the color image into the depth upsampling process. Using a window partitioning scheme, linear complexity in image resolution can be achieved, so it can be applied to high-resolution images. The proposed method of guided depth super-resolution outperforms other state-of-the-art methods through extensive experiments.
Keywords: super-resolution; deep learning; depth maps; attention; multimodal; transformers super-resolution; deep learning; depth maps; attention; multimodal; transformers