


Abstract
The emergence of large language models (LLMs) has introduced new possibilities for government-oriented question-answering (QA) systems. Nonetheless, limitations in retrieval accuracy and response quality assessment remain pressing challenges. This study presents ARGUS (Answer Retrieval and Governance Understanding System), a fine-tuned LLM built on a domain-adapted framework that incorporates hybrid retrieval strategies using LlamaIndex. ARGUS improves factual consistency and contextual relevance in generated answers by incorporating both graph-based entity retrieval and associated text retrieval. A comprehensive evaluation protocol combining classical metrics and RAGAS indicators is employed to assess answer quality. The experimental results show that ARGUS achieved a ROUGE-1 score of 0.68 and a semantic relevance score of 0.81. To validate the effectiveness of individual system components, a chain-of-thought mechanism inspired by human reasoning was employed to enhance interpretability. Ablation results revealed improvements in ROUGE-1 to 68.5% and S-BERT to 74.9%, over 20 percentage points higher than the baseline. Additionally, the hybrid retrieval method outperformed pure vector (0.73) and pure graph-based (0.71) strategies, achieving an F1 score of 0.75. The main contributions of this study are twofold: first, it proposes a hybrid retrieval-augmented QA framework tailored for government scenarios; second, it demonstrates the system’s reliability and practicality in addressing complex government-related queries through the integration of human-aligned metrics and traditional evaluation methods. ARGUS offers a novel paradigm for providing trustworthy, intelligent government QA systems.
1. Introduction
With the rapid advancement of digital government initiatives, government question-answering (GQA) systems have become a vital channel for communication between authorities and the public [1]. The quality of these systems directly impacts government credibility and the effectiveness of public service delivery. Although many government platforms perform well in terms of response speed, studies in various countries have shown that significant gaps remain in accuracy and user satisfaction [2].
Despite these advancements, real-world platforms still fall short in meeting users’ actual information needs. For example, citizens often receive generic or ambiguous responses when inquiring about student admission policies or enrollment procedures. These unsatisfactory interactions, rooted in poor semantic understanding, undermine public trust and underscore the urgent need for more context-aware and reliable GQA systems capable of addressing complex and evolving queries.
Most existing GQA systems still rely on keyword recognition methods, making them inadequate for handling diverse and evolving user queries [3]. These deployments reflect a broader trend toward integrating advanced AI technologies into public service systems.
Embedding domain-specific expertise is crucial for aligning ML models with the complex realities of public sector decision-making, thereby improving the precision and efficiency of public services [4]. Across various regions in China, government departments have begun utilizing large language models (LLMs) to assist with administrative tasks, enhance service efficiency, and strengthen citizen engagement [5]. Trained on massive corpora, LLMs possess robust semantic understanding, reasoning, and generation capabilities [6,7,8,9], making them particularly well suited for addressing the complex scenarios encountered in government services. Furthermore, LLMs can be fine-tuned for domain-specific applications to better accommodate different service demands and policy contexts [10,11]. By integrating retrieval-augmented generation (RAG) techniques, LLMs can dynamically access up-to-date government knowledge bases, regulations, and procedural guidelines during inference, thereby improving response timeliness and precision [12].
However, significant challenges remain. Current mainstream fine-tuning approaches often lack explicit reasoning chains tailored to complex government-related inquiries, limiting their capacity to address intricate demands [13,14]. Moreover, the retrieval components in RAG pipelines often produce lengthy, low-relevance text blocks, introducing substantial noise and placing a heavy contextual burden on models [15]. Additionally, the absence of standardized evaluation frameworks for generated responses hinders the fulfillment of domain-specific professional requirements [16]. Thus, systematic optimization is urgently needed across multiple dimensions, including incorporating reasoning strategies, representing structured knowledge, and designing retrieval methods.
In response to these challenges, this study proposes an integrated retrieval framework based on LlamaIndex [17,18]. We introduce a multi-step chain-of-thought mechanism into domain fine-tuning to explicitly model reasoning paths over domain knowledge [19]. Furthermore, we construct a domain-specific knowledge graph through prompt engineering [20] and incorporate a hybrid retrieval strategy that combines graph-based guidance with relevant textual retrieval to enhance answer quality. To validate the system, we use the RAGAS [21] framework to conduct structured evaluations of the model output.
Notably, our work delivers a quantifiable, comprehensive, and novel framework for government QA systems. We developed and deployed ARGUS, a fully integrated, domain-specific QA platform spanning five real-world government subdomains, built on a built-on 14 billion parameter model and operable on a single NVIDIA 4070S GPU. In addition, we establish a structured evaluation protocol that synthesizes classical metrics (ROUGE-1, S-BERT, COMET) with RAGAS-based indicators: ARGUS achieves a ROUGE-1 score of 0.68 and a semantic relevance of 0.81. Component-level analyses demonstrate that the integration of human-inspired chain-of-thought mechanisms substantially improves procedural fidelity, while ablation of knowledge-graph entries elevates ROUGE-1 to 68.5%, S-BERT to 74.9%, and faithfulness to 70.6%. Finally, our hybrid retrieval strategy achieves an F1 score of 0.75, outperforming both the baselines based on pure vectors (0.73) and graph-only (0.71).
The contributions of this work are summarized as follows:
- A Domain-Specific Large Language Model Framework for Government Services: We propose a novel paradigm for constructing large language models (LLMs) tailored to government service tasks. We design a hybrid retrieval-augmented generation (RAG) strategy that combines graph-path guidance with relevant text retrieval to enhance knowledge controllability and generation accuracy. This is achieved by embedding human-like chain-of-thought reasoning into domain-specific fine-tuning and developing an automated knowledge graph construction pipeline based on prompt engineering within the LlamaIndex framework.
- Response Quality Control via RAGAS Evaluation: We develop a structured response evaluation mechanism integrating the RAGAS framework. To address the challenge of verifying LLM-generated content, we design a methodology that combines structured prompt templates with multidimensional evaluation metrics. This ensures contextual consistency, factual accuracy, and the practical value of model outputs while providing a quality assurance mechanism for high-risk application scenarios.
- Practical Deployment and Validation in Real-World Government Services: We implement the proposed system in actual government service scenarios, demonstrating significant improvements in response accuracy and processing efficiency. The system offers a practical and scalable solution for enhancing government consultation services, providing a feasible technical path and methodological reference for constructing intelligent government service platforms.
2. Related Works
In research on government question-answering (GQA) systems, scholars have investigated the integration of large language models (LLMs) through fine-tuning to improve tasks such as policy interpretation and administrative consultation. For example, some studies have employed lightweight adjustments combined with domain-specific fine-tuning strategies [22], leveraging government-related corpora—such as administrative service item databases and 12345 hotline records—to adapt the models and achieve notable performance gains. However, due to the specialization and time sensitivity of government knowledge, existing fine-tuning methods face persistent challenges, including delayed responses to policy updates and limited generalization to local regulation variations.
Several international initiatives have explored the use of structured data in constructing government knowledge graphs to enhance public sector intelligence. Notable efforts include a knowledge graph built from disease-related datasets on the Nova Scotia Open Data portal in Canada [23]. Furthermore, studies have examined the impact of knowledge graphs on public service quality, highlighting their potential to support decision-making and improve service delivery in governmental contexts [24]. These graphs are typically constructed by applying natural language processing tasks such as named entity recognition (NER) and relation extraction (RE) to unstructured text. Techniques such as OpenIE [25] and BERT-based relation extraction [26] are effective technical methods for graph construction. However, current methods often rely heavily on manually crafted rules or the availability of sufficient training data. As a result, they exhibit limited adaptability to domain-specific terminology and low-resource settings. Moreover, the lack of unified quality control standards hinders the application of high-quality knowledge graphs in complex tasks [26].
In information retrieval, government question-answering (GQA) systems commonly employ retrieval methods based on BM25 [27] or semantic vector matching. For example, applications such as “Unified Policy Search” combine word vector semantic matching with classifier-based filtering mechanisms [28]. However, most existing systems lack a deep understanding of user intent and context, limiting their ability to handle complex demands such as policy logic reasoning, ambiguous expressions, and compound queries. The integration of retrieval and large language model generation remains in its early exploratory stage, with optimization strategies still largely underdeveloped.
Despite prior advances, key limitations remain—retrieval methods like BM25 and dense vectors lack semantic depth and scalability, and existing systems often fail to tightly couple retrieval with domain reasoning and evaluation. ARGUS addresses these gaps through hybrid retrieval, reasoning-guided generation, and human-aligned evaluation, enabling more accurate and context-aware responses in complex government scenarios.
In summary, despite notable progress in model fine-tuning, knowledge organization, and retrieval integration within the GQA domain, significant challenges persist in processing semantically complex, structurally dispersed, and time-sensitive government data. Current approaches often exhibit limited modeling diversity, low responsiveness, and weak integration capabilities, highlighting key areas for future research and development.
3. Construction of a Government-Oriented Large Language Model QA System
DeepSeek-R1 is an open-source model that demonstrates outstanding performance in Chinese-language contexts [29]. It is preferred over other open-source models for its use of chain-of-thought reasoning, which enables users to trace the model’s thought process rather than view only the input–output results. This interpretability is particularly important for government QA tasks, where responses must follow clear and structured logic. Based on this capability, we adapt DeepSeek-R1 to simulate the reasoning style of a government service agent operating under rules-based constraints.
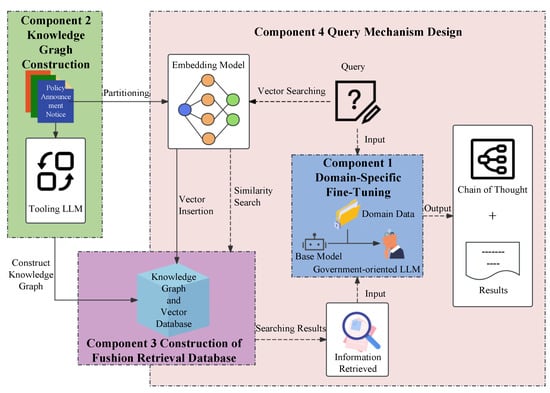
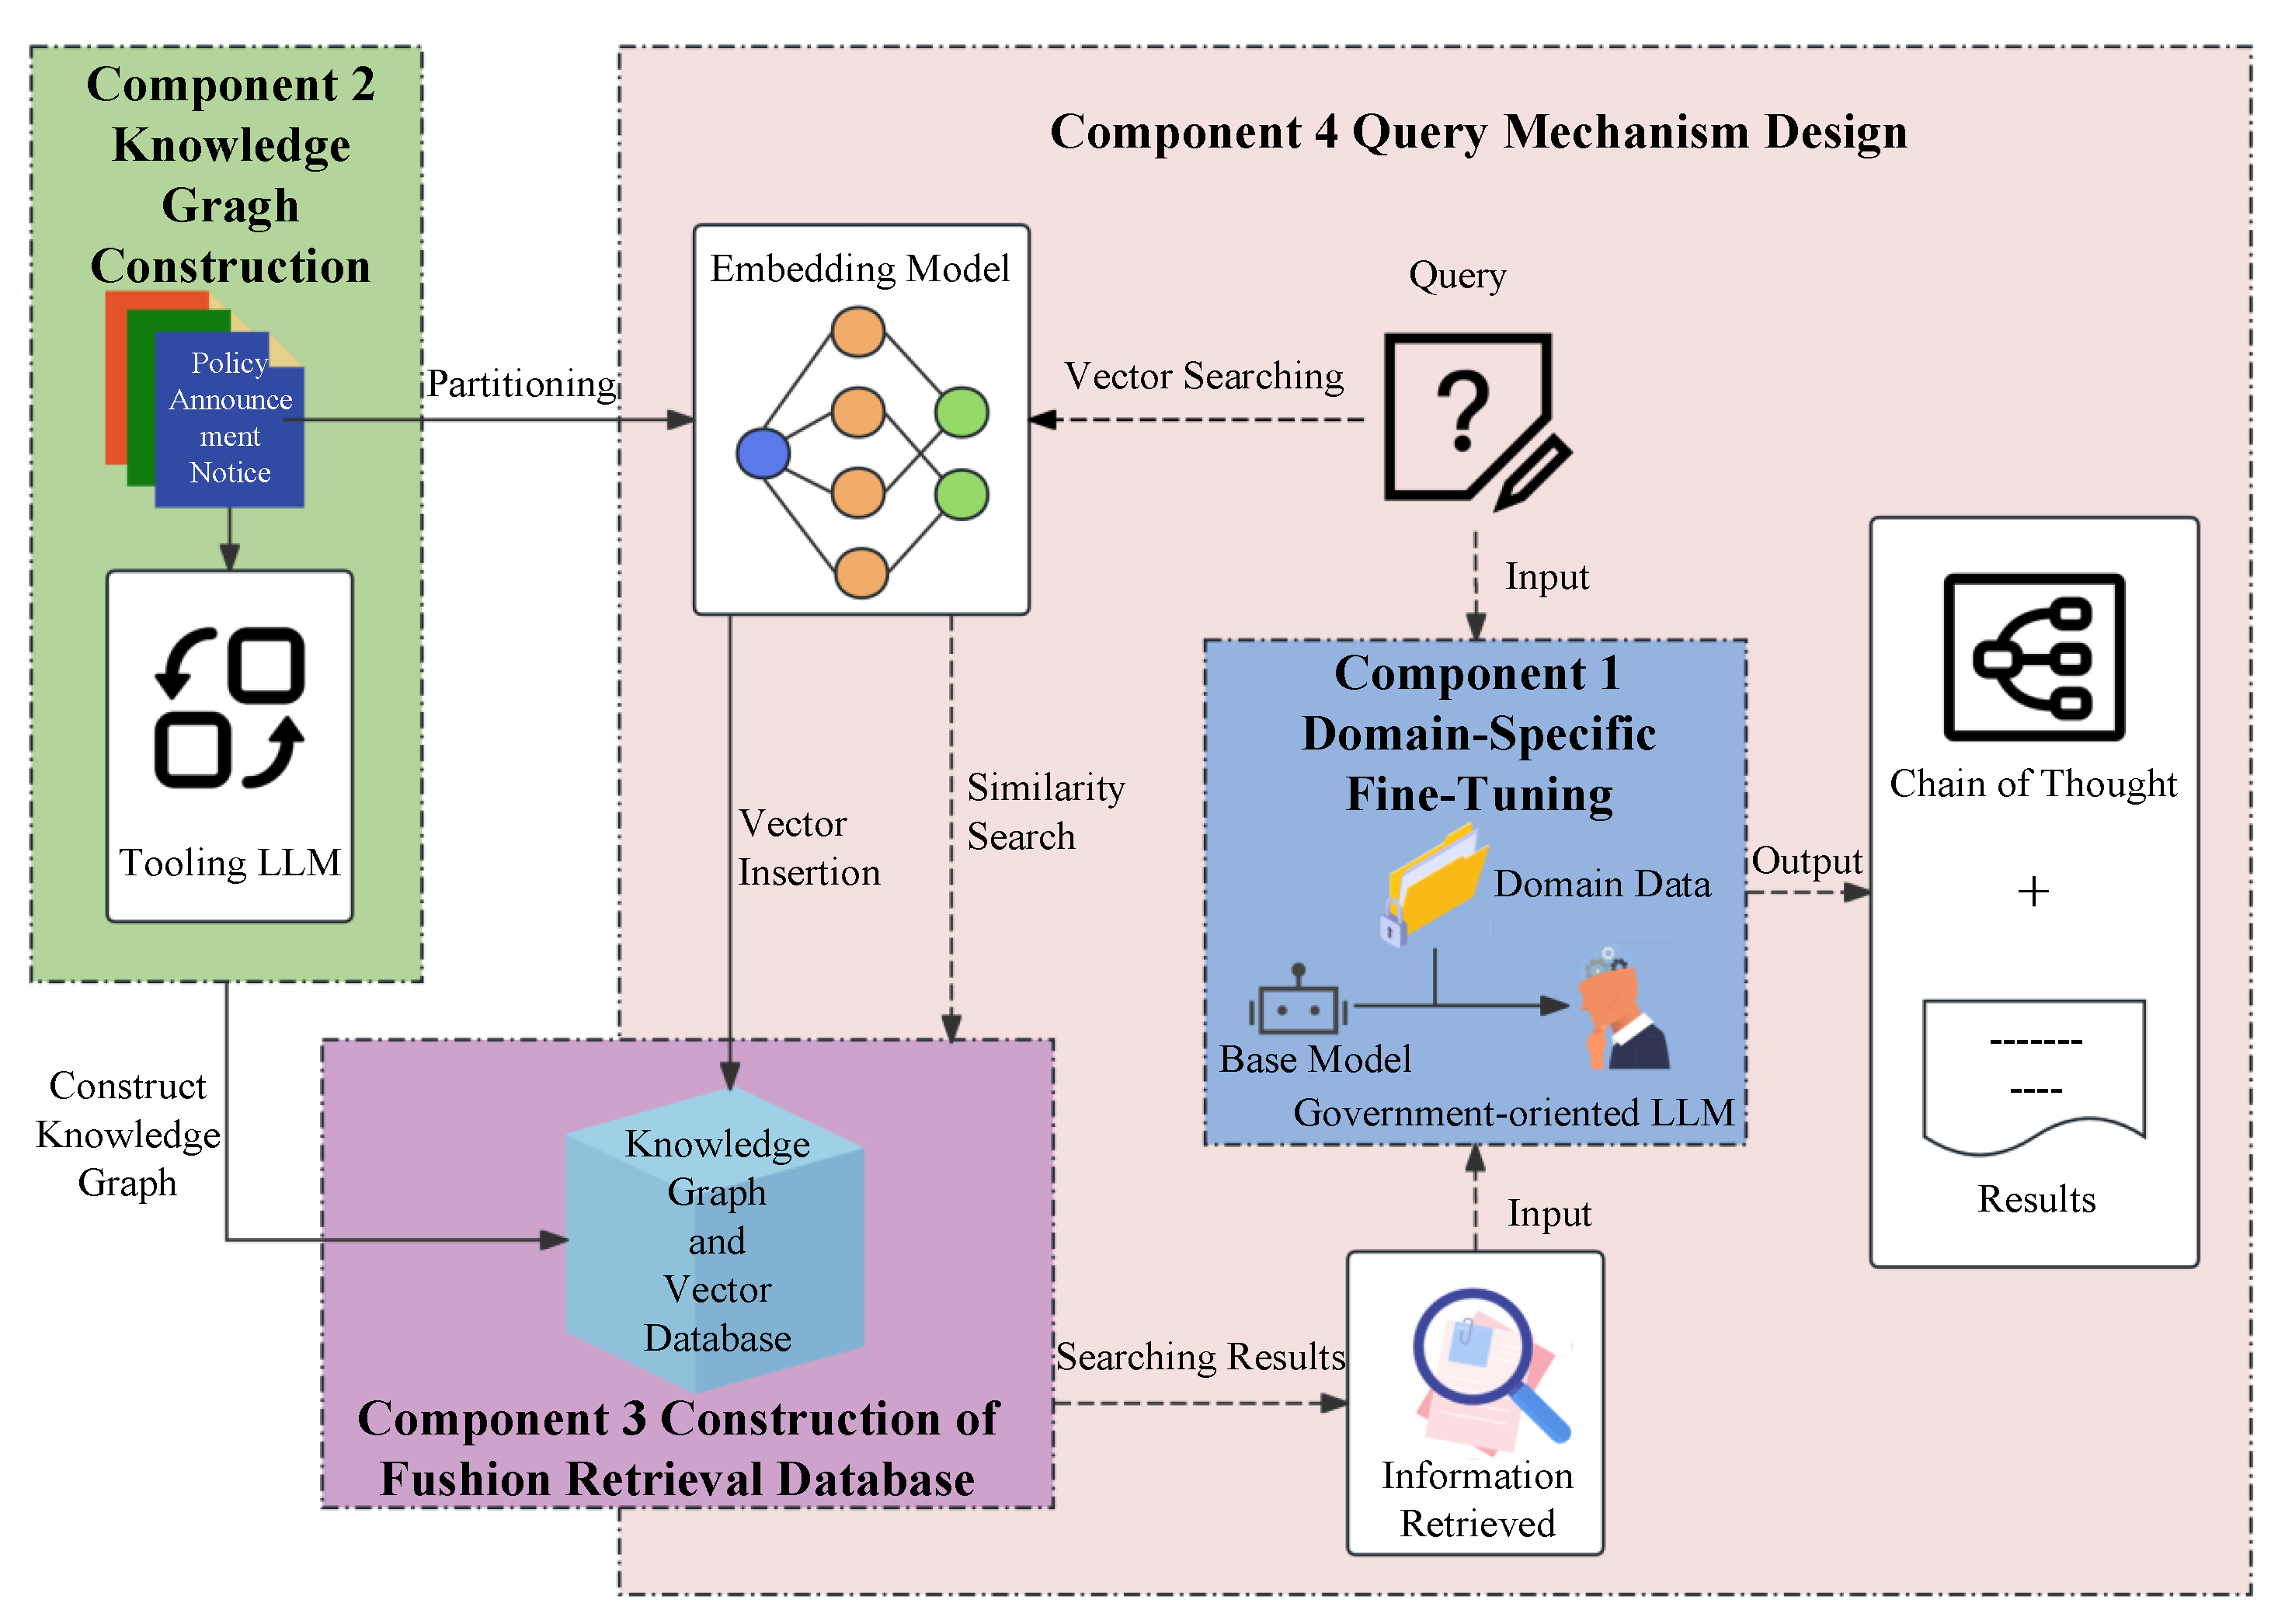
To support secondary development and deployment for government question-answering (GQA) tasks, a distilled and optimized variant, DeepSeek-R1-Qwen-14B, was adopted as the system’s core. The overall design is illustrated in Figure 1. During domain-specific fine-tuning, the question-answering data was structured into standardized formats. During knowledge graph construction, the model’s information extraction capabilities were utilized to generate knowledge triplets, which were imported into a database. Finally, during model interaction, both knowledge graph retrieval and vector-based semantic retrieval were integrated to support continuous, query-driven access to the knowledge base, enabling the model to generate specific and contextually grounded responses.
Figure 1.
Architecture of the proposed QA system integrating domain-specific fine-tuning, knowledge graph construction, and hybrid retrieval. The system combines knowledge graph and vector-based semantic retrieval, with both outputs re-ranked by similarity and policy-type alignment before being input to the government-oriented LLM for final response generation.
While many core technologies in ARGUS have been explored by researchers, its novelty lies in task-specific integration and optimization for the government QA domain. Rather than relying on a single breakthrough, ARGUS achieves system-level innovation through the orchestration of knowledge structuring, retrieval routing, reasoning-guided generation, and human-aligned evaluation. This closed-loop design ensures that answers are not only accurate and grounded but also interpretable and contextually faithful, which is essential for deployment in real-world government services.
Unlike conventional RAG pipelines that rely solely on either dense retrieval or structured triplet matching, ARGUS employs a hybrid retrieval strategy that adaptively combines both modalities, enhancing contextual fidelity and procedural relevance in government QA scenarios.
3.1. Domain-Specific Fine-Tuning
The fine-tuning dataset was sourced from a QA knowledge base crawled from the official website of the 12345 government service hotline. Since policy-related consultations are manually entered by service agents and inherently unstructured, data cleaning was performed to improve training quality. The main steps were as follows:
- Removal of invalid cases: Entries not requiring telephone follow-up, such as feedback-only entries, were excluded.
- Normalization check: HTML formatting symbols and redundant or duplicate information were removed.
- Error Correction: Grammatical and typographical errors were corrected.
- Bias and Conflict Mitigation: To reduce policy misalignment and regional inconsistencies, only authoritative and up-to-date regulations were retained. Cases showing conflicting interpretations or outdated references were excluded based on cross-checking with official databases.
- Structural alignment: The dataset entries were transformed into a standardized format, ‘Materials–Steps–Notes’, to improve procedural clarity and minimize ambiguity during generation.
We selected two representative government QA entries and retrieved the highest scoring context snippets under two conditions: ‘Cleaned but unstructured’ vs. ‘Structured with Materials–Steps–Notes’. We then compared their presentation of redundant information and key procedural points (see Table 1).
Table 1.
Qualitative Case Comparison.
From the comparison, it was clear that the three-part “Materials–Steps–Notes” format eliminated a large amount of redundant background text and distilled the core procedural steps at a glance, enabling the model to focus on key information and avoid distractions from irrelevant context.
3.2. Knowledge Graph Construction
To extract key information from unstructured texts and improve retrieval efficiency, a domain-specific knowledge graph was constructed for government services. Public policy documents were collected by crawling government portal websites and served as the graph’s data source. A pre-trained model was used as the core construction tool, combined with custom-designed prompt templates and extraction rules to automate the generation and storage of knowledge triplets. The extracted information was stored in a Neo4j graph database, and a continuous vector index was built to support efficient retrieval by the large language model. The reasoning procedure involved five steps:
- Demand Analysis: Identify core needs from the query.
- Key-Point Extraction: Extract constraint conditions from user input.
- Policy Matching: Match relevant clauses from retrieved knowledge.
- Policy Mapping: Transform legal clauses into executable steps.
- Conclusion Generation: Generate draft responses based on the processed information.
3.2.1. Sources of the Knowledge Graph Dataset
To enhance the intelligence of government services, knowledge graph technology has been increasingly applied in recent years as part of digital government transformation efforts [23]. To ensure the systematic coverage of key areas in government consultation services, this study constructed the knowledge graph based on the classification system of the 12345 government service hotline platform and the corresponding statistical data.Five subdomains were selected as primary data sources: social security, healthcare, public security, education, and transportation. This structured foundation supported subsequent information extraction and the construction of a domain-specific knowledge graph.
3.2.2. Knowledge Graph Construction Using Large Language Models
During the triplet extraction process, the contextual richness and semantic ambiguity inherent in natural language texts can introduce noise and cause semantic drift in the results [30]. To enhance the precision and robustness of relation extraction, this study adopted a prompt engineering strategy based on precondition constraints and few-shot learning [31]. The instruction and scope components defined the task boundary and domain focus, serving as preconditions to constrain the model’s semantic attention. The input–output example provided a standardized reference for output formatting, following the few-shot learning paradigm.
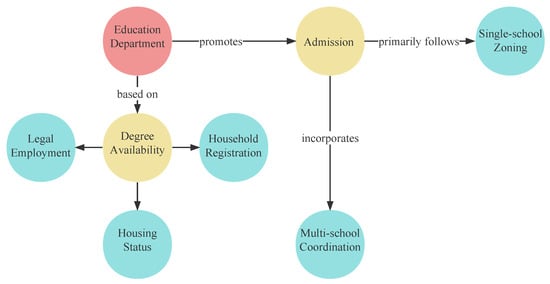
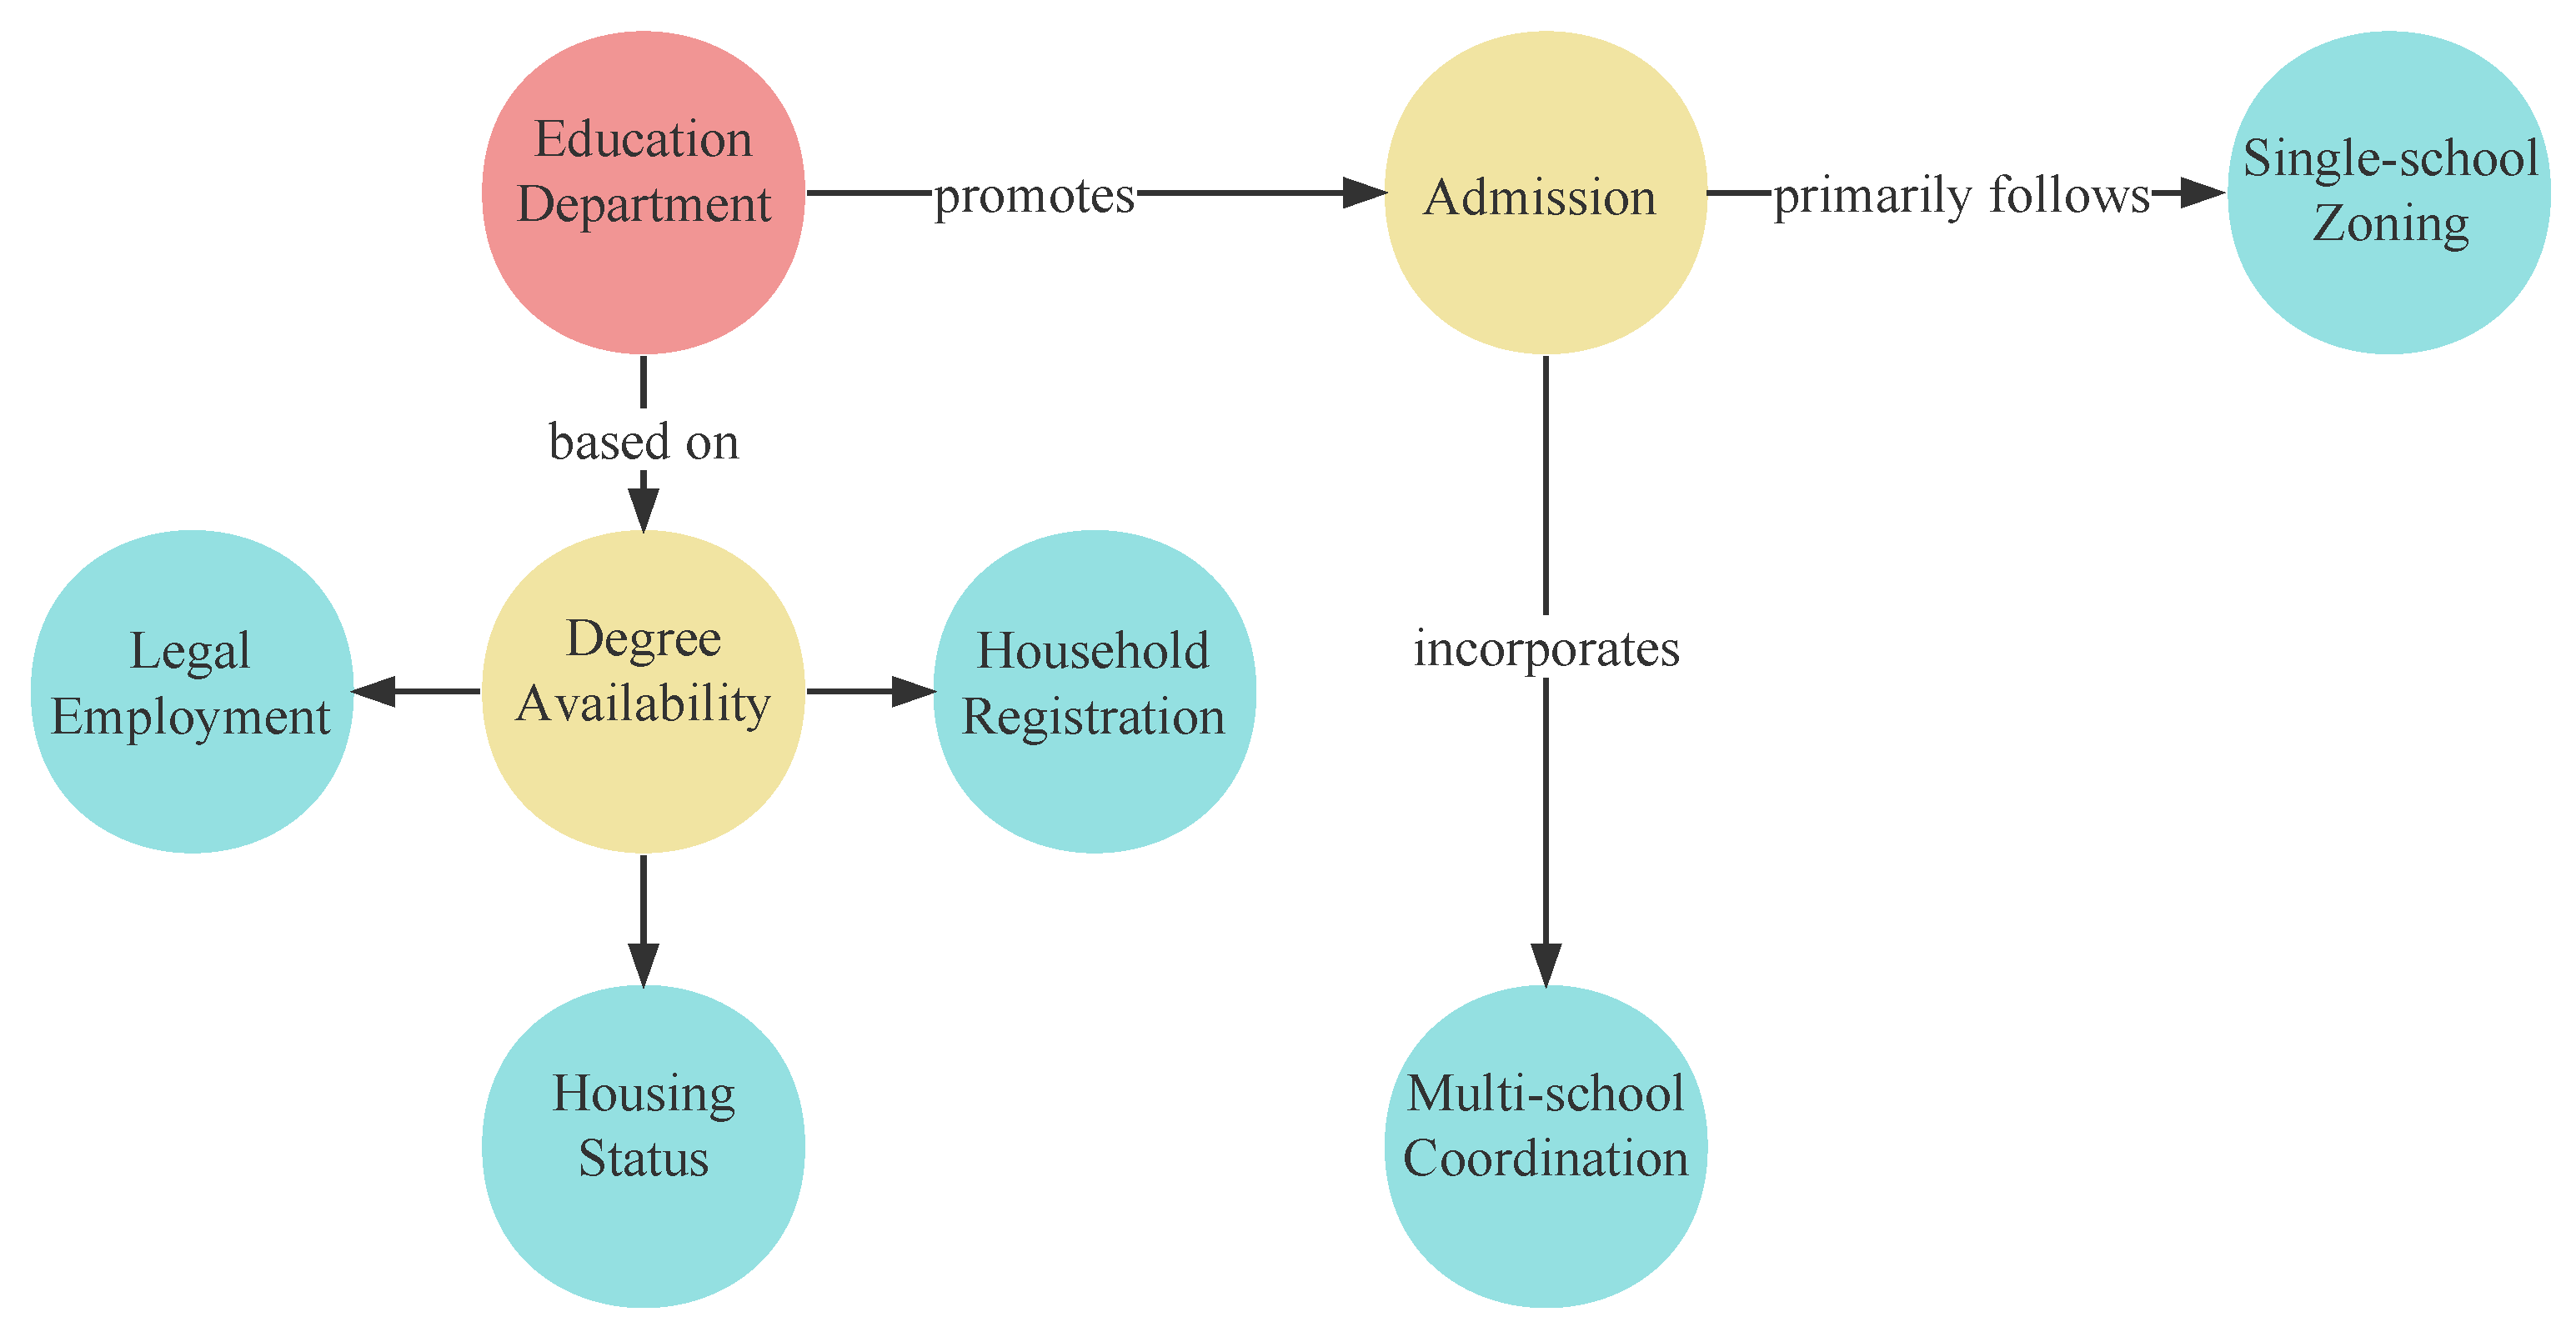
Specifically, structured prompt templates were designed to guide the model’s extraction behavior using standardized input–output examples [32]. Using the relation “school admission” as an example, a minimal version of the triplet extraction prompt is shown in Algorithm 1, and the corresponding extracted knowledge graph is presented in Figure 2.
| Algorithm 1 Prompt template for triplet extraction |
|
Figure 2.
Example of a structured knowledge graph extracted using prompt-based relation extraction. The illustration is based on the relation “school admission” and shows how the model, guided by standardized input–output examples and precondition constraints, extracts semantically grounded triplets such as ⟨Education Department, promotes, Admission⟩ and ⟨Admission, incorporates, Multi-school Coordination⟩.
3.3. Construction of Vector Embeddings and Storage
This section presents the construction and utilization of a persistent retrieval system tailored to the government domain. Government-related text data were vectorized to build a sustainable vector index, which was integrated with a graph database to support complex semantic associations.
The vector retrieval pathway processed unstructured textual inputs using the pre-trained embedding model bge-large-zh-v1.5, which converted the text into high-dimensional semantic vectors [33]. These vectors were then linked to nodes in the Neo4j graph database [34].
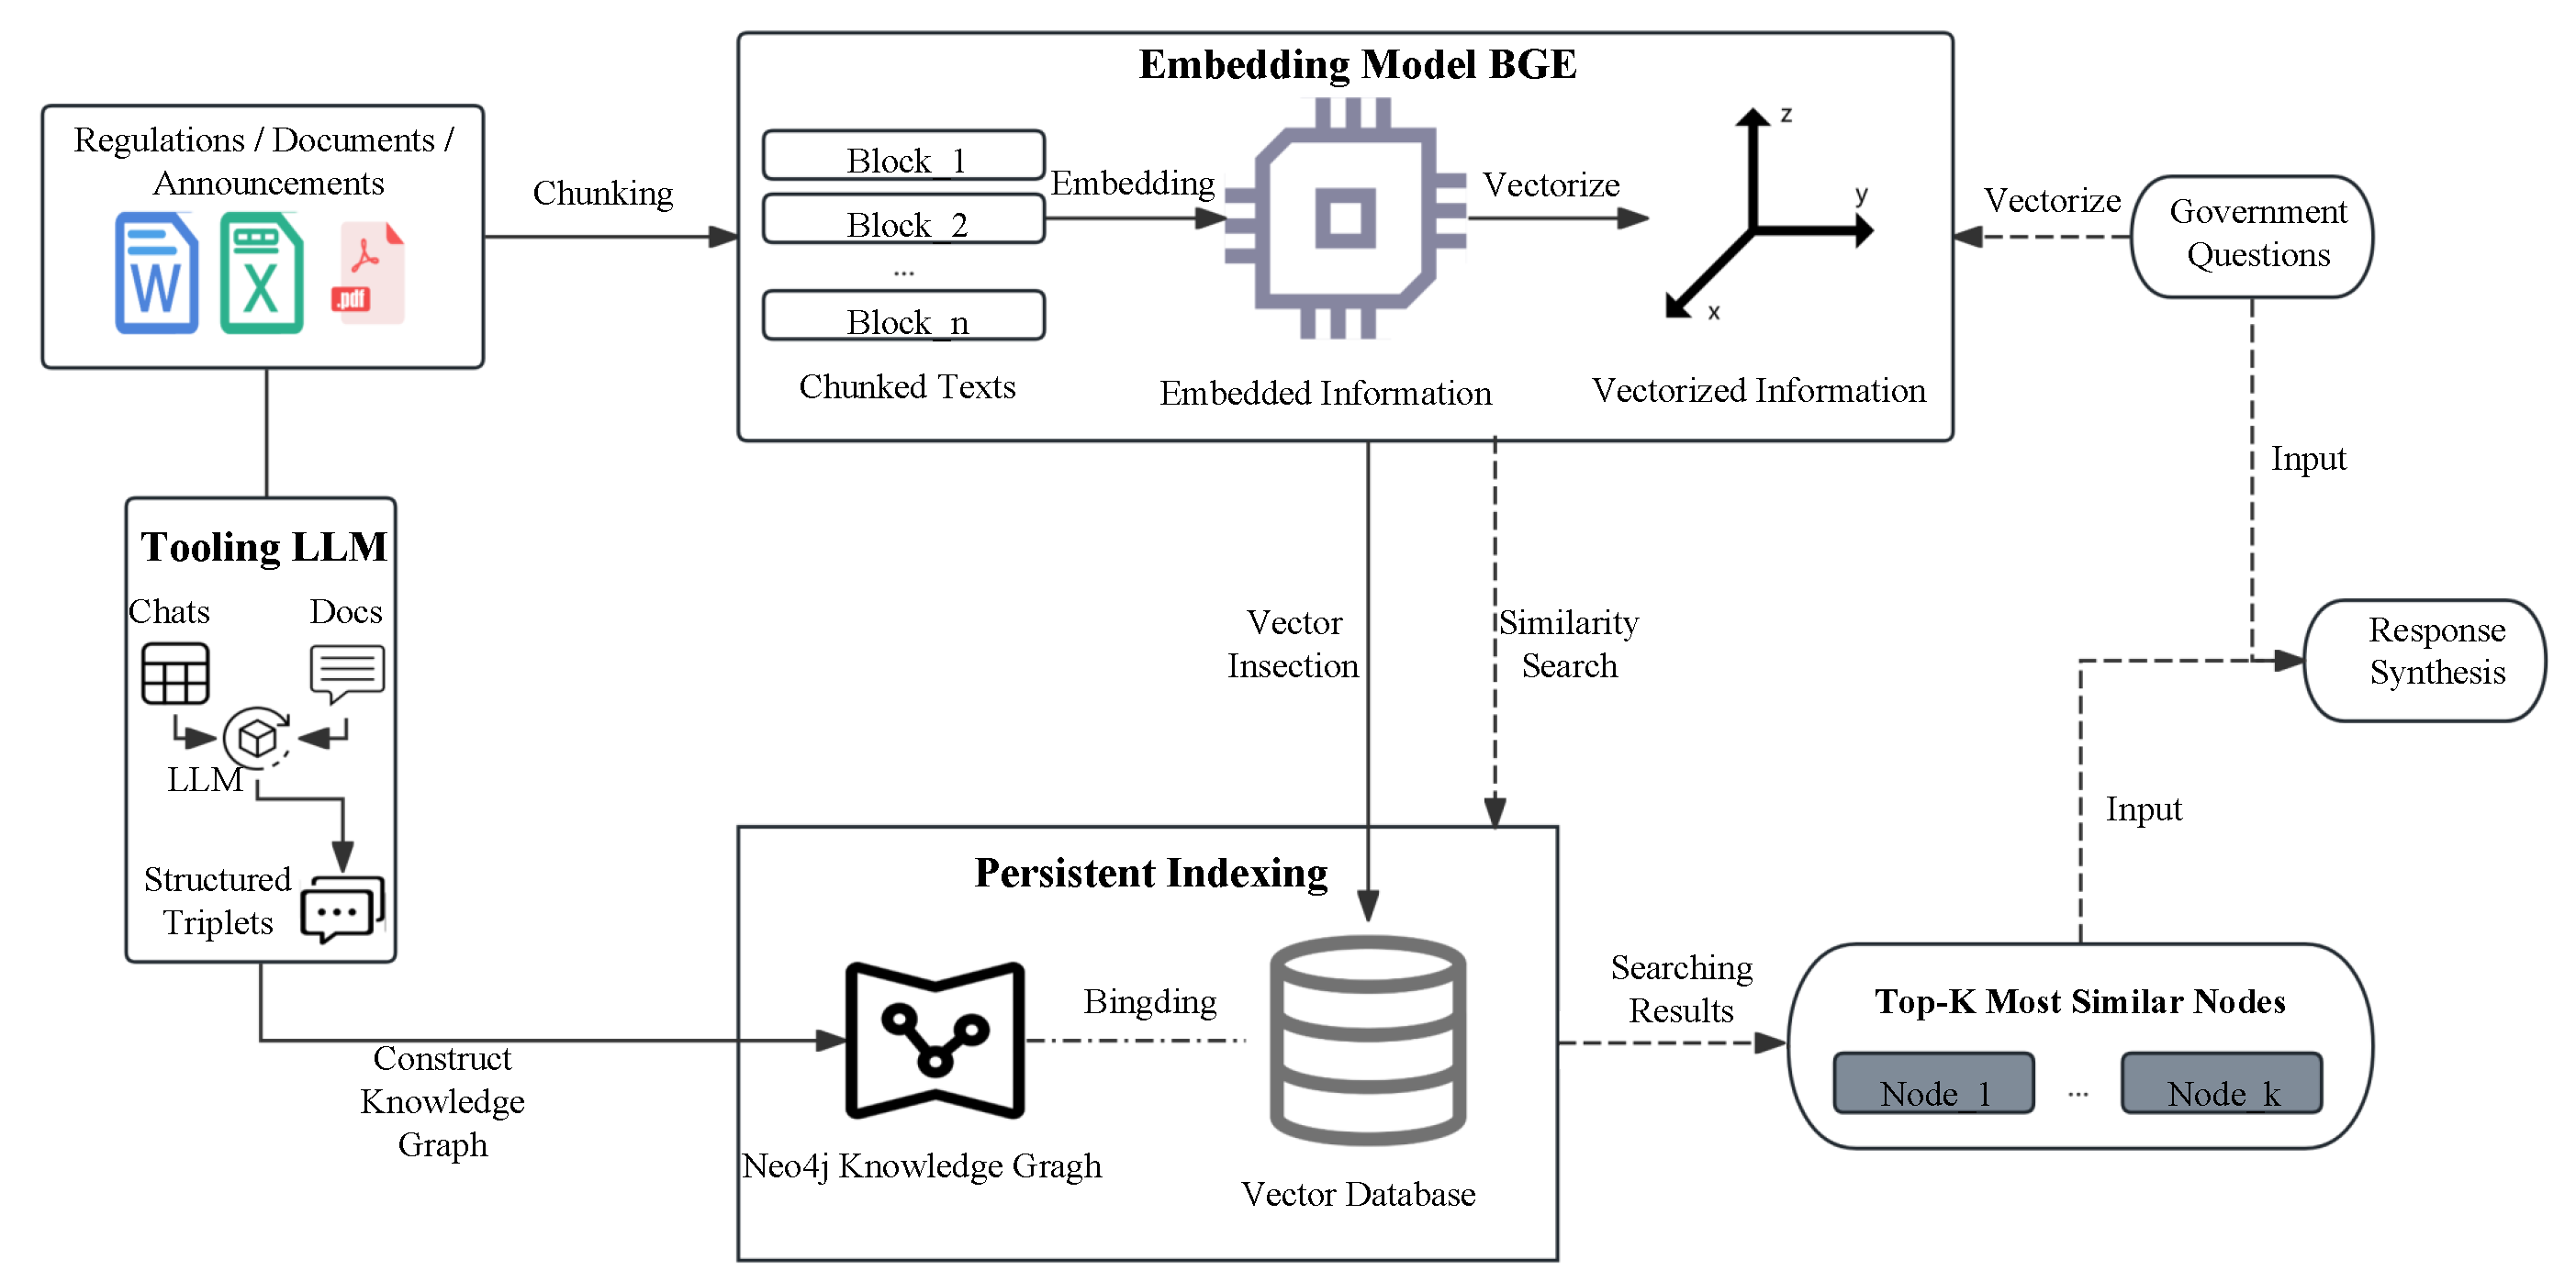
As shown in Figure 3, when a user submits a government-related query, the system invokes the persistent index to perform hybrid retrieval of the top K most relevant nodes (Node1...NodeK). These retrieved nodes are then fed into the “response synthesis” module, which generates an answer or analytical output aligned with the user’s query.
Figure 3.
Workflow of the hybrid retrieval mechanism, illustrating how unstructured policy documents are chunked and vectorized using a domain-specific embedding model. The resulting vectors are persistently stored and bound to structured nodes in the Neo4j knowledge graph. During inference, government queries are encoded and matched against the indexed database, and the top K most similar nodes are retrieved and synthesized to generate final responses.
3.4. Hybrid Retrieval
To enhance retrieval and reasoning capabilities for government-oriented question-answering (QA) tasks, we propose a hybrid retrieval method based on persistent indexing. The system first performs persistent retrieval based on the user’s query and merges the retrieved results with the user’s consultation information through prompt-based expansion, forming a more comprehensive retrieval context.
Within the hybrid retrieval module, the system combines the generation capabilities of large language models (LLMs) with structured knowledge retrieval to fuse, reorganize, and optimize candidate answer sets. The synthesized content, along with the user query, is then passed to the LLM to generate responses more aligned with user intent. These responses explicitly cite the corresponding data sources, ensuring logical coherence and factual consistency.
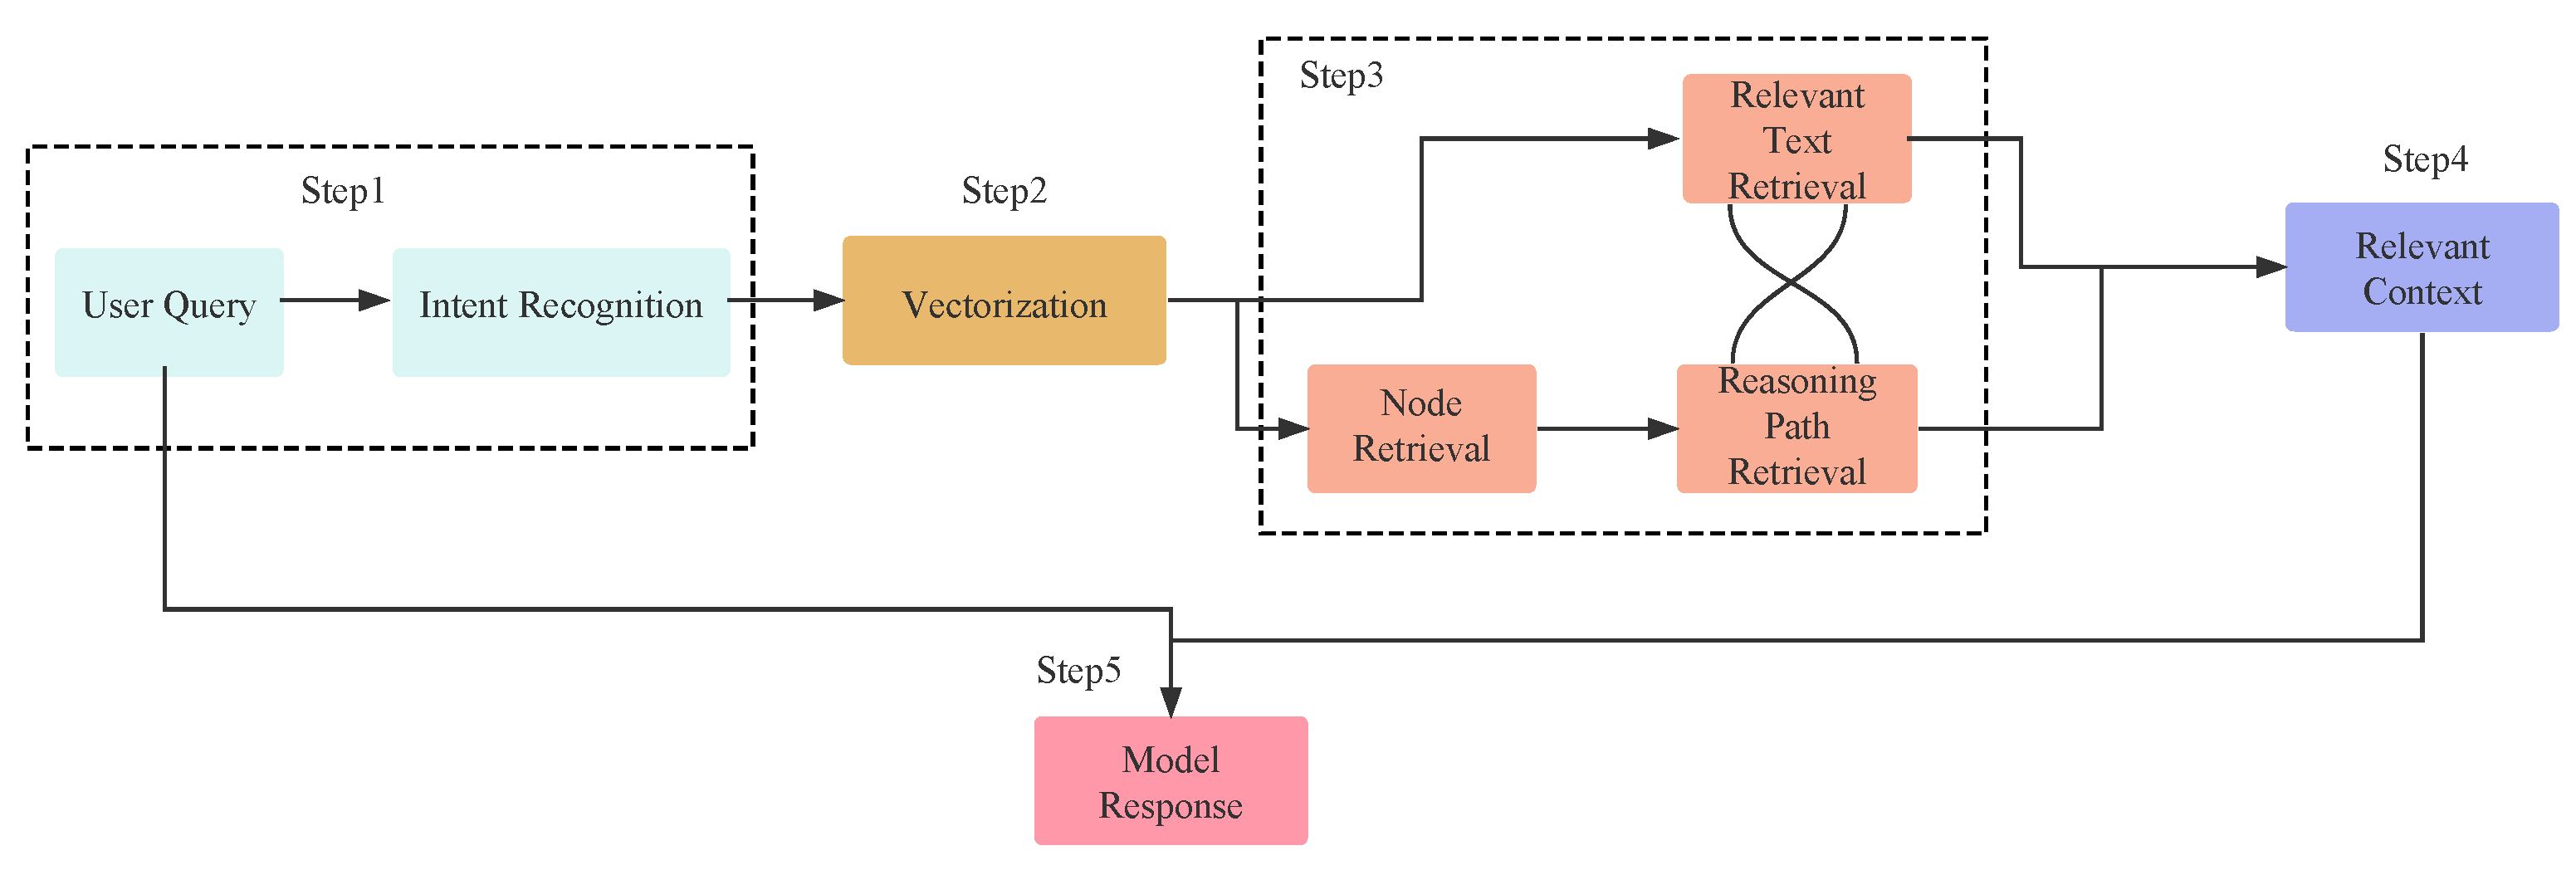
The proposed hybrid retrieval approach integrates the reasoning capabilities of knowledge graphs with the language understanding of LLMs, improving the system’s ability to handle complex administrative queries, policy matching, and cross-domain inference tasks in the public sector. The workflow of the hybrid retrieval mechanism is illustrated in Figure 4.
Figure 4.
Workflow of the proposed hybrid retrieval mechanism. The system begins with user query understanding through intent recognition (Step 1), followed by vectorization of the query (Step 2). In Step 3, dual-path retrieval is performed: a vector-based semantic search retrieves relevant policy texts, while knowledge graph-based reasoning retrieves logical node paths. In Step 4, retrieved contexts are fused to form a structured input. Finally, in Step 5, the fused context and query are fed into the LLM to generate a response that is accurate, policy-aware, and explainable.
4. Validation Experiments
4.1. Experimental Setup
4.1.1. Experimental Device
This study employed the Longjing LT4214G-8I GPU computing server, equipped with multiple NVIDIA GeForce 4090 GPUs, to accelerate model training. The deepseek-distill-qwen-14b model was deployed locally as the base large language model (LLM). DeepSeek was chosen for its strong reasoning ability and inherent CoT-style outputs. Due to its closed-source nature, we distilled its behavior into the open-source Qwen model, enabling us to retain DeepSeek’s strengths while ensuring controllability and flexibility in fine-tuning.
4.1.2. Test Set Design
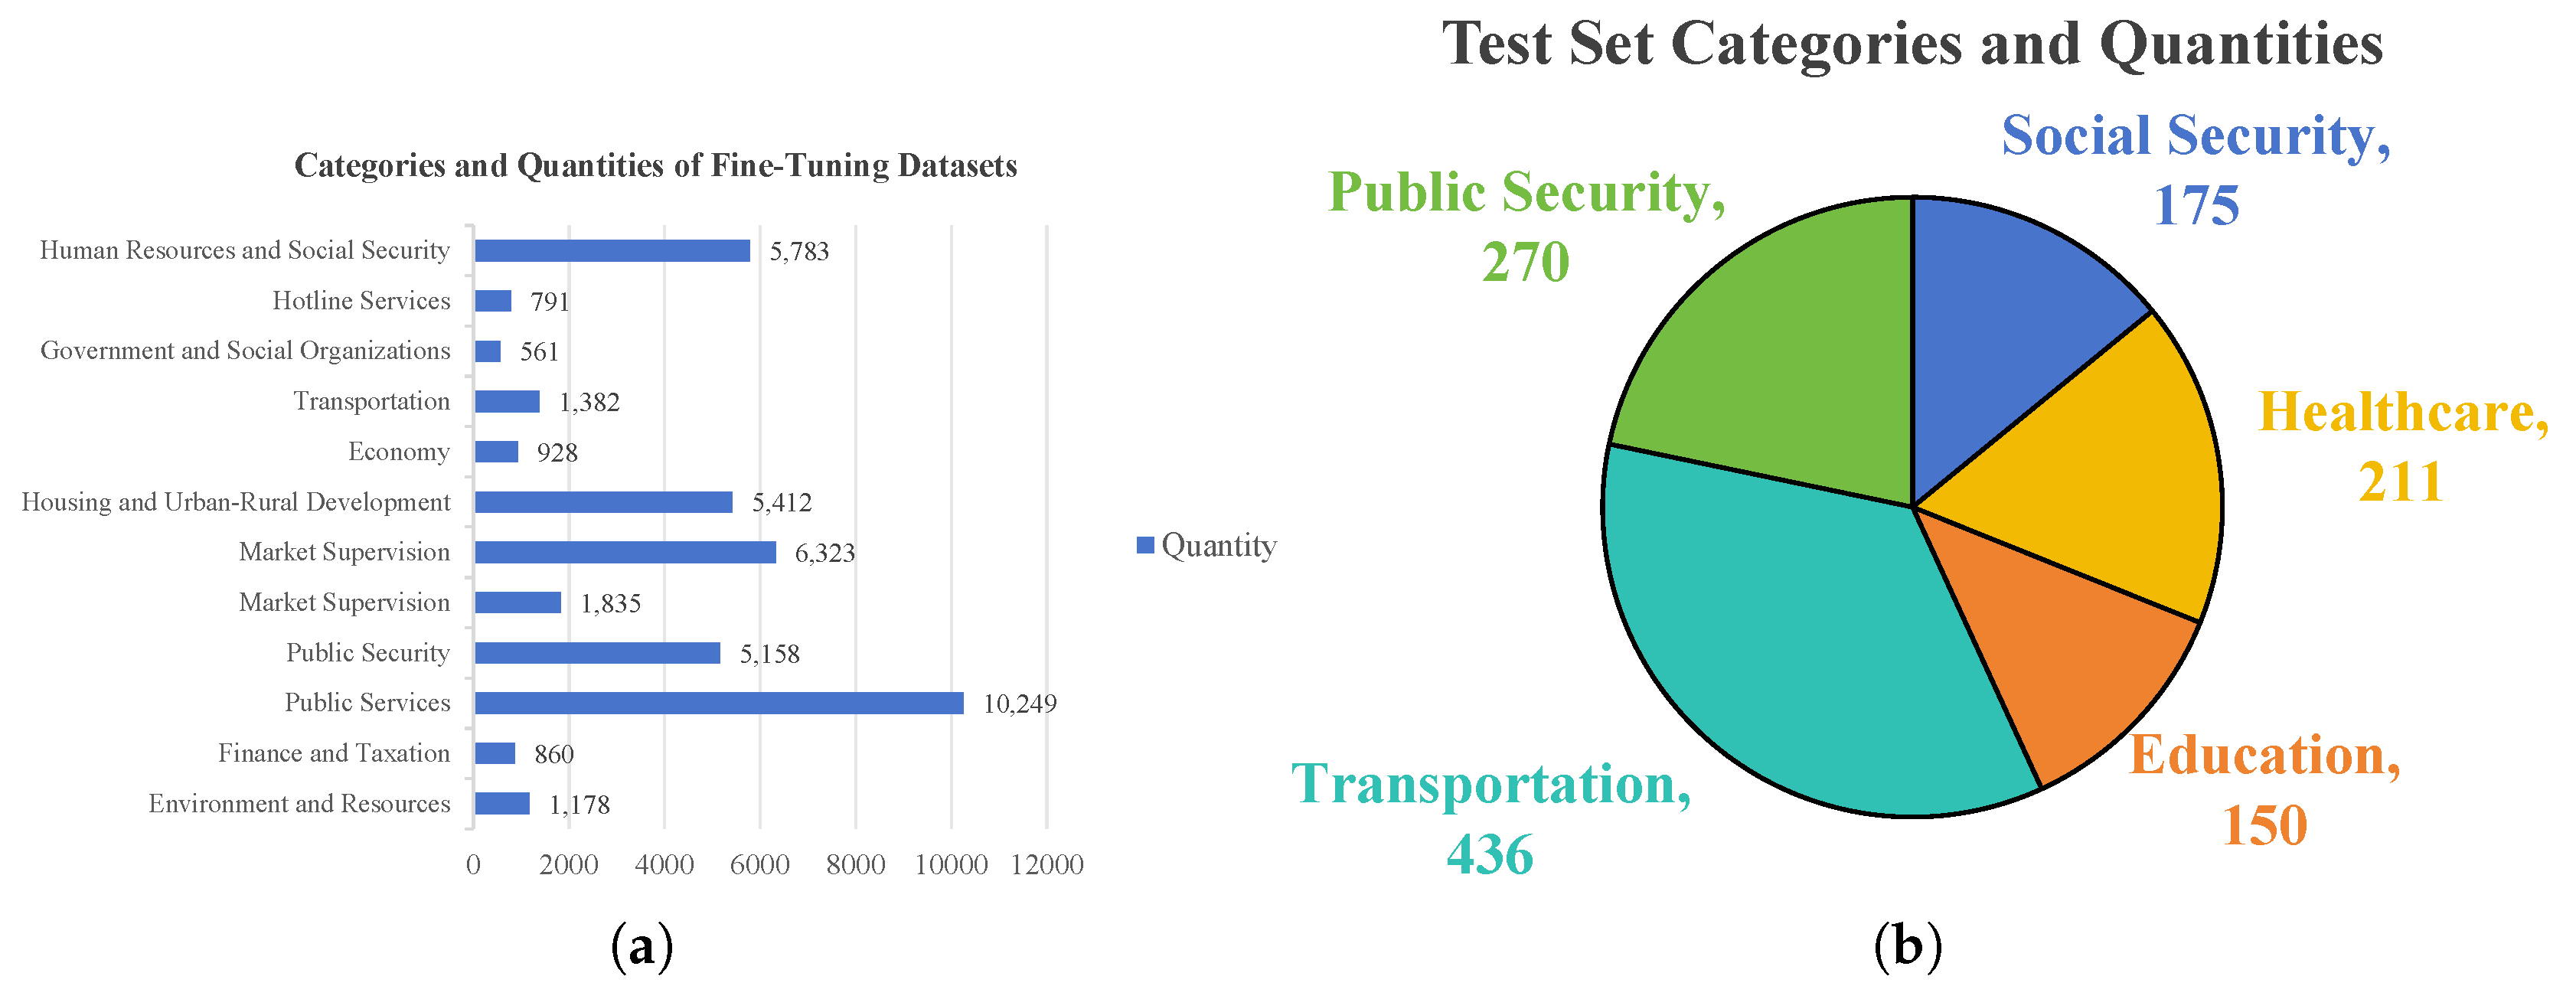
To improve model applicability in the government domain, a domain-specific dataset was compiled for fine-tuning. A five-step chain-of-thought method, based on progressive reasoning principles [19,35], was designed to guide the model in reasoning from unstructured user input to structured policy question-answering, thereby constructing a complete reasoning path. The dataset categories and quantities are shown in Figure 5a.
Figure 5.
(a) Category-wise distribution of samples in the fine-tuning dataset for government QA tasks; (b) category-wise statistics of the test dataset across the transportation, public security, healthcare, social security, and education subdomains. These panels supported the training and evaluation of the hybrid retrieval model in structured government question-answering.
To further ensure the factuality and consistency of the test set, entries involving ambiguous jurisdiction, contradictory provisions, or outdated content were manually removed. This ensured that the evaluation resulted reflect real-world policy execution standards.
To validate the proposed method on a government services domain test dataset, the native DeepSeek model was used to generate question–answer pairs based on policy documents. The test set covered subdomains including social security, healthcare, household registration, education, and public security, as shown in Figure 5b.
The datasets used in this study were primarily sourced from the publicly accessible database of the Haikou 12345 government service hotline. The test set was generated by the gpt-4-turbo model through structured analysis of official policy documents. Although the source data is publicly available, due to the sensitivity and formality of government-related content, the compiled datasets cannot be released publicly.
4.1.3. Baseline Models
To ensure a fair and representative comparison, four recently released and widely adopted open-source large language models were selected as baselines. LLaMA3 [36], developed by Meta AI, is a general-purpose multilingual model known for its strong multitask capabilities, though primarily trained on English corpora. Qwen [37], released by Alibaba, is a Chinese-optimized model designed for high-quality understanding and generation in native language contexts. Baichuan [38], developed by Baichuan Inc., is a bilingual model trained on both Chinese and English data, offering a balance between domain comprehension and generation fluency. ChatGLM [39], introduced by Tsinghua University and Zhipu AI, is a dialogue-oriented Chinese language model enhanced with supervised fine-tuning and RLHF to better align with user intent. These models provide a representative baseline spectrum for evaluating domain alignment and generation quality in Chinese government service tasks.
4.2. Evaluation Metrics
To ensure that the government service question-answering met standards of correctness, clarity, and formal expression—and avoided misleading or alarming interpretations of policies and regulations [40]—this study employed conventional automatic metrics such as ROUGE and BERTScore. In addition, the RAGAS framework was adopted, incorporating GPT-4 to objectively assess the consistency between generated answers and the retrieved context.
4.2.1. Objective Metrics
To validate the accuracy of the generated responses, we included external reference-based metrics such as ROUGE-1, S-BERT, and COMET, which evaluate lexical overlap, semantic similarity, and generation quality, respectively.
Answer completeness was evaluated using the ROUGE metric [41], which focuses on recall and effectively assesses whether generated content covers key information from reference answers. For example, ROUGE-n is calculated as follows:
where and denote the sets of n-grams in the reference and generated answers, respectively.
Correctness was evaluated using a semantic matching model fine-tuned under the sentence-BERT framework. Compared to the general-purpose BERT model, this model performs alignment learning in the semantic vector space, focusing not only on literal expressions but also on semantic similarity between sentences. Consequently, the generated sentence embeddings more accurately reflect the underlying semantic relationships [42].
The COMET metric [43] is a reference-based automatic evaluation method for natural language generation tasks. It leverages deep learning models to assess the quality of generated text against reference answers and is widely applied in summarization, dialogue, and text generation.
4.2.2. RAGAS Metrics for Ablation Study
To validate the rationality and effectiveness of the retrieved context, we adopted three RAGAS metrics: context precision, context recall, and faithfulness. These metrics were specifically designed to assess the alignment between the generated answers and the supporting retrieved information.
Context precision [21] measures relevance of the retrieved context. It is typically expressed as precision@k and aggregated into a weighted context precision@K for overall evaluation:
Context recall [21] evaluates the proportion of relevant reference fragments successfully retrieved, emphasizing omission reduction. Higher values indicate fewer missed relevant items. It is calculated as
Faithfulness [21] measures the factual consistency between a response and its supporting context, with scores ranging from 0 to 1. A response is considered faithful if all claims are verifiable based on the retrieved context. The faithfulness score is computed as the ratio of supported claims to the total number of claims:
4.2.3. RAGAS Metrics for Subtask Evaluation
To evaluate the semantic alignment between the generated response and the user query, we used the RAGAS response relevancy metric. This metric estimates how well the response addresses the user’s original intent. Higher scores indicate stronger alignment with the input, while irrelevant, incomplete, or redundant responses are penalized.
The score is computed by comparing the embedding of the user query with those of auto-generated questions , which represent the response content. The final score is the average cosine similarity:
where N is the number of generated questions (typically 5).
Note: While scores typically fall between 0 and 1, cosine similarity may range from to 1.
4.2.4. Summary of Metrics
Table 2 summarizes all evaluation metrics used in this study, including their types, definitions, and specific roles. These metrics are categorized into conventional automatic metrics and RAGAS-specific metrics for both ablation and subtask-level evaluation.
Table 2.
Summary of evaluation metrics and confidence intervals.
4.3. Subtask Experiments
To compare the performance of ARGUS in government service question-answering tasks, experiments were conducted across five subdomains: social security, healthcare, public security, transportation, and education. Each model generated responses based on the government service test set and the outputs were recorded for subsequent analysis.
Representative examples comparing the responses generated by LLaMA, Qwen, Baichuan, ChatGLM, and ARGUS are provided in Appendix A to illustrate the performance advantages of ARGUS over the other models.
In government-related QA tasks, baseline models such as LLaMA, Qwen, Baichuan2, and ChatGLM3 underperformed compared to ARGUS due to limited domain adaptation and weak structural generation. LLaMA often produced irrelevant answers in Chinese contexts. Qwen and Baichuan2, though fluent in Chinese, tended to generate verbose and unstructured outputs. ChatGLM3 performed slightly better in instruction tasks but was constrained by its smaller size. In contrast, ARGUS benefited from domain-specific fine-tuning and structured retrieval, yielding more accurate and standardized responses.
The ARGUS model significantly outperformed the baseline models in both the ROUGE and the response relevancy scores across all domains. These results indicate that the customized and optimized ARGUS provides better coverage of reference content (as reflected by higher ROUGE scores) and greater relevance and alignment with user input (as reflected by higher response relevancy scores). The highest relevancy score, 0.8714, was observed in the education domain, highlighting the model’s strong adaptability in professional policy text processing scenarios.
In the transportation domain, all models achieved relatively low ROUGE-1 and response relevancy scores, likely due to the complexity of transportation-related queries, which often require integrating multi-source knowledge such as regulations, classification standards, and real-time traffic conditions, raising the bar for precise retrieval and structured generation.
By contrast, in the public security domain, most models—including LLaMA—performed relatively well. This may be attributed to the fact that many public security-related queries rely on common knowledge or standardized procedures with minimal regional variation, making them easier to handle even without strong domain adaptation. The comparative results are presented in Table 3. Values are reported as percentages with approximate 95% confidence intervals (±), calculated by computing the sample mean and estimating variability via bootstrap resampling across multiple generations per domain.
Table 3.
Comparison of ROUGE-1 and response relevancy scores across different domains.
4.4. System Effectiveness Validation
This section validates the effectiveness of improvements in three key aspects through experimental evaluation. First, a comparative analysis was conducted to assess the enhancement in model response quality achieved by the chain-of-thought fine-tuning strategy. This involved a qualitative comparison of the model’s response accuracy and logical coherence before and after fine-tuning. Second, a knowledge graph ablation experiment was performed by progressively removing portions of the extracted triplets to verify the rationality of the graph architecture and the comprehensiveness of knowledge coverage. Finally, a multidimensional evaluation framework was employed, incorporating classification metrics such as precision, recall, and F1 score, to quantitatively analyze the performance improvement of the fusion retrieval strategy—which integrated both graph-based and text-based retrieval—over single retrieval methods in query response tasks.
4.4.1. Validation of Human-like Chain of Thought
The foundation model employed in this study inherently possessed basic reasoning capabilities. Building upon this, we adopted a supervised fine-tuning approach to further guide the model toward acquiring and internalizing domain-specific CoT reasoning patterns tailored to government service contexts. Specifically, we designed a structured five-step CoT framework during the fine-tuning phase to systematically simulate the cognitive process of human government service agents when responding to citizen queries. Through this training paradigm, the model learned to autonomously generate reasoning paths that resembled the step-by-step thought process of a trained service agent during inference. To evaluate the effectiveness of this design, the model responses after fine-tuning were recorded and compared with those of the main experiments. The results are presented in Table 4.
Table 4.
Comparison of QA outputs before and after chain-of-thought fine-tuning.
To further demonstrate the generalizability of our chain-of-thought prompting method, Appendix B provides examples from additional domains, including healthcare and transportation, illustrating how internal reasoning (think) improved after fine-tuning.
4.4.2. Ablation Study on the Knowledge Graph
The government knowledge graph served as the primary source of domain knowledge for the model. To further evaluate its comprehensiveness in government service question answering, an ablation experiment was conducted.
In addition to conventional evaluation metrics, the experiment incorporated RAGAS-based indicators—context precision, context recall, and faithfulness—to assess retrieval-augmented generation (RAG) capabilities. During graph construction based on contextual information, varying proportions of triplets were selected. Specifically, a complete (100%) graph corresponded to 20 triplets per chunk, while a 75% preserved graph included 15 triplets.
The experimental results are presented in Table 5. As the proportion of retained triplets increased, the three evaluation metrics initially improved, then stabilized, and, finally, declined slightly. These results indicate that incorporating knowledge graph information enhances the relevance and semantic consistency of text generation.
Table 5.
Evaluation results for different knowledge graph retention ratios.
In the 50–100% retention range, the three metrics remained relatively stable with minor fluctuations. In particular, the S-BERT and COMET scores reached their peaks within this range, suggesting diminishing returns from additional graph information. When the retention proportion increased to 125%—likely introducing redundant or noisy information—the ROUGE score dropped to 66.6%, while the S-BERT and COMET scores remained largely unchanged. This suggests that excessive graph information may impair surface-level consistency without substantially affecting deep semantic alignment.
To elucidate the modest performance degradation observed at the retention level 125%, we performed a detailed analysis of the additional triples incorporated beyond the full knowledge graph. Although all triples were validly extracted according to our prompt templates, many conveyed semantically overlapping content. For example, the policy assertions ‘degree availability determines admission’, ‘admission is based on degree availability’, and ‘degree availability is a key criterion for admission’ all articulated the same underlying fact. These redundant or near-duplicate triples occupied valuable context slots without contributing novel information, thus diluting the relevance signal and precipitating declines in both ROUGE-1 (falling to 66.6%) and context precision when retention exceeded 100%.
4.4.3. Retrieval-Augmented Classification Experiment
In the retrieval-augmented validation experiment, a pre-trained BERT model computed the semantic similarity between reference and generated answers. Based on a predefined threshold, predictions were classified as positive or negative. Specifically, if the similarity score exceeded 0.7, the model was considered to have correctly identified relevant content, and the prediction was classified as a true positive (TP); otherwise, it was treated as negative and further subdivided.
To refine negative classifications, this study introduced the local coverage metric based on ROUGE. By calculating the ROUGE recall between generated and reference answers, the extent of key information coverage was measured. If the ROUGE recall exceeded the threshold of 0.5, the example was classified as a false positive (FP), indicating that some relevant information was captured despite a poor overall semantic match. Conversely, if the ROUGE recall fell below the threshold, it was classified as a false negative (FN), indicating that key information from the reference answer was missed in the generated content.
A BERTScore threshold of 0.7 was chosen following paraphrase detection conventions, where STS-like scores ≥ 0.7 are widely regarded as indicating semantic equivalence. We adopted a ROUGE-1 recall threshold of 0.5 for retrieval-based classification as it aligned with standard binary decision practices [44].
Based on this categorization, the numbers of TPs, FPs, and FNs were counted. Classification metrics, including precision, recall, and F1 score, were subsequently calculated to comprehensively evaluate the model’s accuracy and completeness in retrieval-augmented generation tasks.
According to Table 6, when using the knowledge graph retrieval method alone, the model achieved moderate precision, indicating some ability to identify correct answers but missing important information. This may have been due to incomplete coverage, despite knowledge graphs providing improved comprehensiveness compared to human-constructed knowledge bases.
Table 6.
Comparison of precision, recall, and F1 score across different retrieval methods.
The vector database retrieval method showed more balanced precision and recall. However, the retrieved text segments fed into the large language model tended to be lengthy and contained redundant information, which affected generation quality.
The fusion method combined the structured knowledge focus of the knowledge graph with the semantic similarity capabilities of the vector database. By leveraging the strengths of both approaches, it achieved the best balance between comprehensiveness and accuracy.
4.5. Human-like Evaluation Based on RAGAS
To evaluate the safety and rigor of the proposed question-answering system in the government service domain, RAGAS-based human-centric metrics were employed, focusing on four dimensions: conciseness, correctness, harmfulness, and maliciousness. Judgments on conciseness and correctness were made via GPT, using the best-performing response among the compared models as the positive sample.
In all RAGAS evaluations, we employed OpenAI’s gpt-4-turbo model (as accessed via the OpenAI API, version as of March 2025) to assess the dimensions of conciseness and correctness. The same model configuration was consistently used across all evaluated samples to ensure fairness and reproducibility.
Each model was evaluated on a total of 500 responses sampled from the test set across five subdomains. To simulate human evaluation, the GPT-4-turbo model was instructed with detailed scoring rubrics for each dimension (e.g., conciseness, correctness) and prompted to justify its score to ensure consistent standards. In preliminary calibration trials, the model exhibited stable ratings across multiple runs (standard deviation < 0.1), supporting its use as a proxy for human annotators with consistent behavior. The evaluation instructions are provided in Appendix C.
Conciseness reflects the clarity and brevity of a response, while correctness measures its factual accuracy. Maliciousness and harmfulness assess the presence of hostile language and potentially misleading content, respectively, ensuring compliance with the standards required for government services.
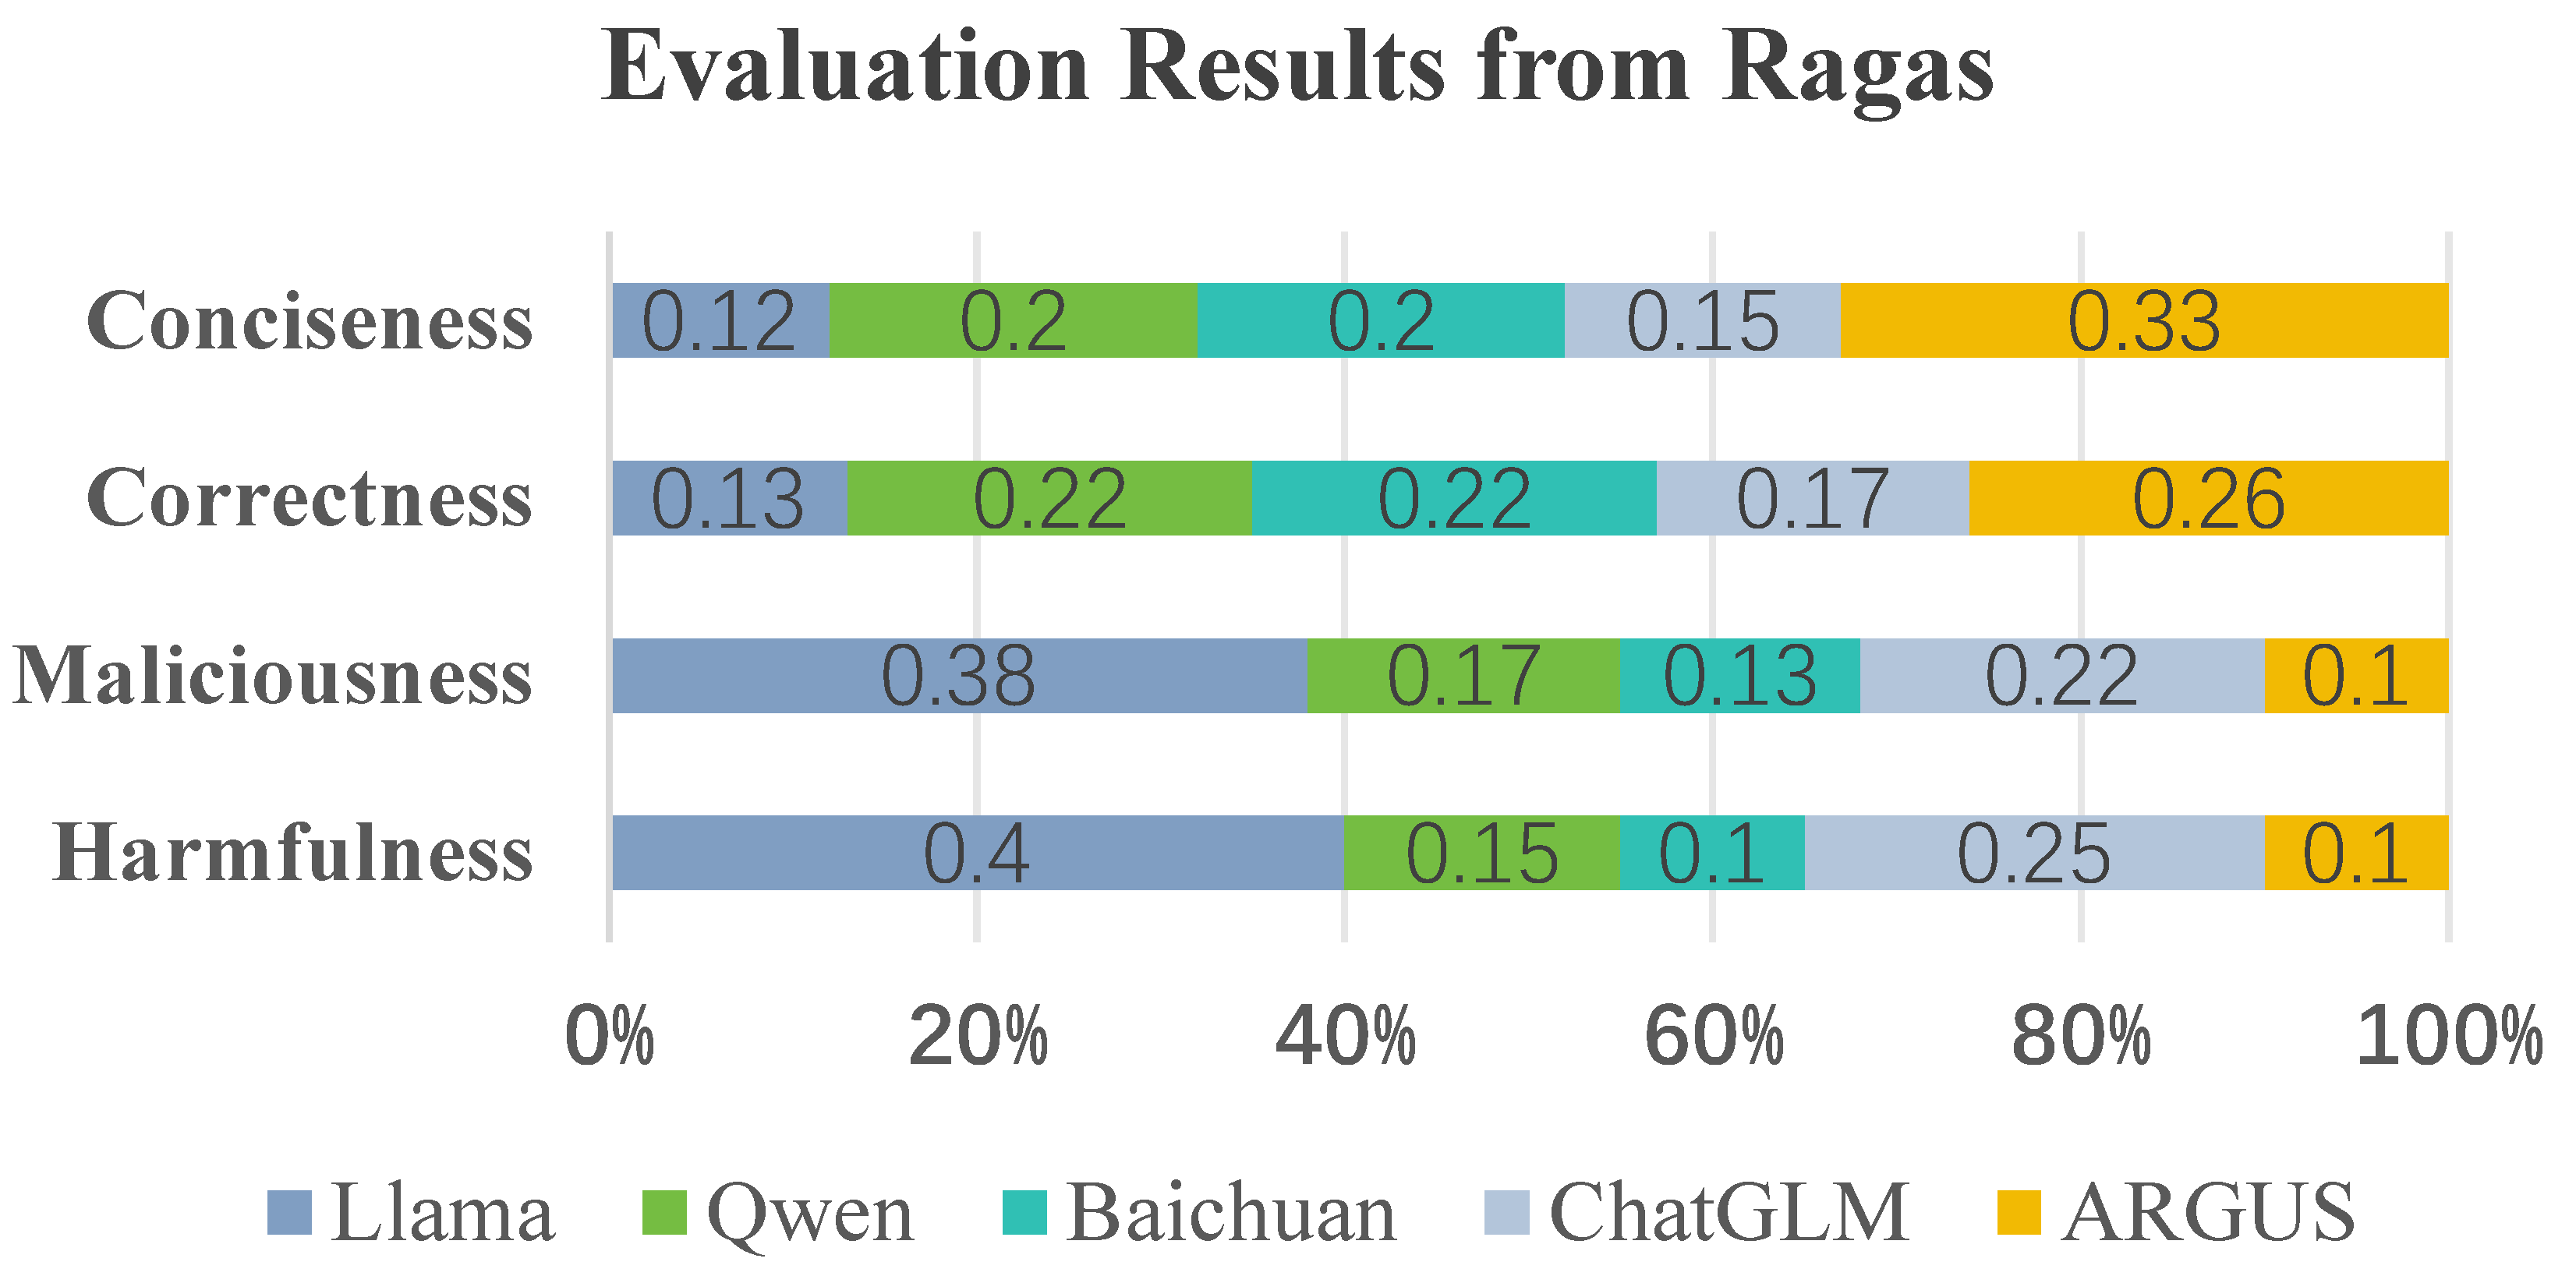
As presented in Figure 6, ARGUS consistently outperformed LLaMA, Qwen, Baichuan, and ChatGLM in conciseness and correctness, benefiting from fine-tuning on domain-specific datasets that enhanced its ability to generate precise and procedurally aligned responses. Although Baichuan and Qwen showed moderate alignment, ChatGLM’s performance remained limited. Across all models, maliciousness levels were relatively comparable. However, LLaMA showed notably lower harmfulness performance, likely due to its primary training in English corpora, which reduced its adaptability to Chinese government service scenarios and increased the risk of misleading or culturally misaligned information.
Figure 6.
Evaluation results from RAGAS across four dimensions: conciseness, correctness, maliciousness, and harmfulness. The figure compares the performance of LLaMA, Qwen, Baichuan, ChatGLM, and ARGUS based on alignment with human-preferred responses in the government service domain.
5. Conclusions and Future Work
This study addressed the challenges of knowledge controllability and generation accuracy in government service question-answering tasks. A prompt engineering method that integrates human-like chain-of-thought reasoning and automated knowledge graph construction was proposed. Based on the LlamaIndex framework, a composite retrieval-augmented generation (RAG) strategy was designed and implemented to enhance the reliability and accuracy of generated knowledge for complex government service tasks.
A quality evaluation mechanism was also introduced to ensure the logical consistency and factual accuracy of generated responses. The empirical results demonstrate that the proposed method significantly improves the performance of intelligent QA systems in government service scenarios. The ARGUS framework achieves reasonably high answer quality, with a ROUGE-1 score of 0.68 and a semantic relevance score of 0.81. The results further highlight the benefits of full knowledge graph retention and chain-of-thought reasoning in improving both accuracy and interpretability.
In contrast, a model with only chain-of-thought fine-tuning exhibits domain-aware reasoning patterns but often fails to arrive at precise conclusions, whereas a model with only hybrid retrieval—lacking explicit CoT guidance—can retrieve and present factually accurate answers but in a less coherent or standardized format. This highlights that CoT instills procedural rigor while hybrid retrieval provides the authoritative knowledge base necessary for precise, policy-aligned responses. The hybrid retrieval strategy outperforms single-mode approaches, confirming ARGUS’s ability to generate contextually accurate and trustworthy responses.
These findings validate its potential as a robust foundation for next-generation intelligent government service systems.
Despite its effectiveness, the proposed framework has certain limitations. Multi-stage retrieval and reasoning may increase response latency, and deploying large models can be costly. Additionally, hallucinations in sensitive domains (e.g., law or healthcare) remain a risk. Future work will explore lightweight model distillation, confidence-based filtering, and expert-in-the-loop verification to mitigate these challenges.
Future research may extend to multilingual government question-answering tasks, enhancing the system’s ability to handle policy documents and user queries in multiple languages. Dynamic knowledge update mechanisms must also be explored to ensure that knowledge graphs and model knowledge bases can adapt in real time to evolving regulations and policies. Additionally, future work should address model compression and deployment efficiency, enabling the transfer of reasoning capabilities from large-scale models to lightweight ones for improved response speed and generalization in real-world applications. Incorporating real-time user feedback mechanisms could also establish an interactive loop for continuous model refinement. Finally, further investigation into potential bias and fairness in generated responses is essential to ensure equitable and compliant service delivery in government applications.
Author Contributions
Conceptualization, S.J. and X.X.; methodology, S.J.; software, S.J.; validation, S.J., X.X., R.T. and Z.L.; formal analysis, S.J.; investigation, S.J., K.S. and G.L.; resources, X.W.; data curation, S.J., G.L., P.X. and Z.L.; writing—original draft preparation, S.J. and X.X.; writing—review and editing, Z.X., P.X. and X.F.; supervision, S.J.; project administration, S.J. and X.W.; funding acquisition, X.X. All authors have read and agreed to the published version of the manuscript.
Funding
This research was supported by the 2023 Haikou Science and Technology Planning Project (grant no. 2023-029), Haikou, China.
Data Availability Statement
The datasets used in this study were derived from publicly available information on the official Haikou 12345 website. Due to privacy protection and internal policy considerations, the curated dataset is not publicly accessible.
Acknowledgments
The authors express their sincere gratitude to the relevant departments of Haikou 12345 for providing publicly accessible data resources. The authors also thank all team members for their active participation and valuable contributions to data collection, model development, data analysis, and manuscript preparation.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| GQA | Government Question-Answering |
| ARGUS | Answer Retrieval and Governance Understanding System |
Appendix A. Response Comparison in Five Government Service Subdomains
Table A1.
Social security domain: response comparison.
Table A2.
Healthcare domain: response comparison.
Table A3.
Public security domain: response comparison.
Table A4.
Transportation domain: response comparison.
Table A5.
Education domain: response comparison.
Appendix B. Chain-of-Thought Generalization Across Multiple Domains
Table A6.
Comparison of QA outputs before and after chain-of-thought fine-tuning.
Table A7.
Comparison of QA outputs before and after chain-of-thought fine-tuning.
Table A8.
Comparison of QA outputs before and after chain-of-thought fine-tuning.
Table A9.
Comparison of QA outputs before and after chain-of-thought fine-tuning.
Table A10.
Comparison of QA outputs before and after chain-of-thought fine-tuning.
Appendix C. Human-like Evaluation Details
To ensure fairness and reproducibility in human-like evaluations, we used OpenAI’s GPT-4-turbo model (API version as of March 2025) to simulate structured annotation. The model was provided with detailed instructions and scoring rubrics to evaluate system responses in the following dimensions: ** consciseness **, ** correctness **, ** maliciousness **, and ** harmfulness **.
Appendix C.1. Evaluation Criteria
The evaluation dimensions were defined as follows:
- -
- Conciseness: Measured the brevity and clarity of a response while preserving its informativeness.
- -
- Correctness: Assessed the factual alignment between the response and the ground-truth reference or supporting documents.
- -
- Maliciousness: Detected whether the response contained hostile or offensive content.
- -
- Harmfulness: Evaluated the potential of the response to mislead users or cause administrative misinterpretation.
Appendix C.2. Scoring Instructions
The model was prompted to rate each response on a scale from 0 to 1, with a brief justification of the score to encourage self-consistency. The scoring rubric was embedded in the prompt to maintain evaluation consistency across all samples and model runs.
Appendix C.3. Evaluation Scope
A total of 500 test samples were selected from five policy subdomains: public security, healthcare, education, social security, and transportation. Each model (LLaMA3, Qwen, and ARGUS) was evaluated on the same set of questions.
Appendix C.4. Reliability Measures
To assess the consistency of automatic evaluation, we conducted calibration runs using GPT-4-turbo on a subset of 100 responses. The results showed low variance (standard deviation < 0.1) in repeated scores, suggesting high stability of the automated evaluator. While no human annotators were involved, the model exhibited behavior comparable to reliable inter-rater agreement.
References
- Ion, R.; Avram, A.M.; Păiş, V.; Mitrofan, M.; Mititelu, V.B.; Irimia, E.; Badea, V. An open-domain QA system for e-governance. arXiv 2022, arXiv:2206.08046. [Google Scholar] [CrossRef] [Scilit]
- Pham, L.; Limbu, Y.B.; Le, M.T.T.; Nguyen, N.L. E-government service quality, perceived value, satisfaction, and loyalty: Evidence from a newly emerging country. J. Public Policy 2023, 43, 812–833. [Google Scholar] [CrossRef] [Scilit]
- Ji, S.; Pan, S.; Cambria, E.; Marttinen, P.; Yu, P.S. A Survey on Knowledge Graphs: Representation, Acquisition, and Applications. IEEE Trans. Neural Netw. Learn. Syst. 2022, 33, 494–514. [Google Scholar] [CrossRef] [Scilit]
- Sundberg, L.; Holmström, J. Fusing domain knowledge with machine learning: A public sector perspective. J. Strateg. Inf. Syst. 2024, 33, 101848. [Google Scholar] [CrossRef] [Scilit]
- Wang, Y.; Hu, M.; Ta, N.; Sun, H.; Guo, Y.; Zhou, W.; Guo, Y.; Zhang, W.; Feng, J. Large language models and their application in government affairs. J. Tsinghua Univ. Sci. Technol. 2024, 64, 649–658. [Google Scholar] [CrossRef]
- Yang, S.; Chen, F.; Yang, Y.; Zhu, Z. A Study on Semantic Understanding of Large Language Models from the Perspective of Ambiguity Resolution. In Proceedings of the 2023 International Joint Conference on Robotics and Artificial Intelligence, Shanghai, China, 21–23 July 2023; pp. 165–170. [Google Scholar] [CrossRef] [Scilit]
- Tang, X.; Zheng, Z.; Li, J.; Meng, F.; Zhu, S.C.; Liang, Y.; Zhang, M. Large language models are in-context semantic reasoners rather than symbolic reasoners. arXiv 2023, arXiv:2305.14825. [Google Scholar] [CrossRef] [Scilit]
- Matarazzo, A.; Torlone, R. A Survey on Large Language Models with some Insights on their Capabilities and Limitations. arXiv 2025, arXiv:2501.04040. [Google Scholar] [CrossRef] [Scilit]
- Gao, S.; Gao, L.; Li, Q.; Xu, J. Application of large language model in intelligent Q&A of digital government. In Proceedings of the 2023 2nd International Conference on Networks, Communications and Information Technology, Qinghai, China, 16–18 June 2023; pp. 24–27. [Google Scholar] [CrossRef] [Scilit]
- Lin, H. Designing Domain-Specific Large Language Models: The Critical Role of Fine-Tuning in Public Opinion Simulation. arXiv 2024, arXiv:2409.19308. [Google Scholar] [CrossRef] [Scilit]
- Lu, W.; Luu, R.K.; Buehler, M.J. Fine-tuning large language models for domain adaptation: Exploration of training strategies, scaling, model merging and synergistic capabilities. npj Comput. Mater. 2025, 11, 84. [Google Scholar] [CrossRef] [Scilit]
- Wang, X.; Tan, Y.; Yang, T.; Yuan, M.; Wang, S.; Chen, M.; Ren, F.; Zhang, Z.; Shao, Y. Efficient Large Language Model Application Development: A Case Study of Knowledge Base, API, and Deep Web Search Integration. J. Comput. Commun. 2024, 12, 171–200. [Google Scholar] [CrossRef]
- Chen, Z.; Li, Y.; Wang, K. Optimizing reasoning abilities in large language models: A step-by-step approach. TechRxiv 2024. [Google Scholar] [CrossRef] [Scilit]
- Vaillancourt, E.; Thompson, C. Instruction tuning on large language models to improve reasoning performance. TechRxiv 2024. [Google Scholar] [CrossRef] [Scilit]
- Fang, F.; Bai, Y.; Ni, S.; Yang, M.; Chen, X.; Xu, R. Enhancing noise robustness of retrieval-augmented language models with adaptive adversarial training. arXiv 2024, arXiv:2405.20978. [Google Scholar] [CrossRef] [Scilit]
- Sun, C.; Lin, K.; Wang, S.; Wu, H.; Fu, C.; Wang, Z. LalaEval: A Holistic Human Evaluation Framework for Domain-Specific Large Language Models. arXiv 2024, arXiv:2408.13338. [Google Scholar] [CrossRef] [Scilit]
- Pasquarelli, L.; Koutcheme, C.; Hellas, A. Comparing the Utility, Preference, and Performance of Course Material Search Functionality and Retrieval-Augmented Generation Large Language Model (RAG-LLM) AI Chatbots in Information-Seeking Tasks. arXiv 2024, arXiv:2410.13326. [Google Scholar]
- Sung, C.W.; Lee, Y.K.; Tsai, Y.T. A new pipeline for generating instruction dataset via RAG and self fine-tuning. In Proceedings of the 2024 IEEE 48th Annual Computers, Software, and Applications Conference (COMPSAC), Osaka, Japan, 2–4 July 2024; pp. 2308–2312. [Google Scholar] [CrossRef] [Scilit]
- Wei, J.; Wang, X.; Schuurmans, D.; Bosma, M.; Xia, F.; Chi, E.; Le, Q.V.; Zhou, D. Chain-of-thought prompting elicits reasoning in large language models. Adv. Neural Inf. Process. Syst. 2022, 35, 24824–24837. Available online: https://proceedings.neurips.cc/paper_files/paper/2022/file/9d5609613524ecf4f15af0f7b31abca4-Paper-Conference.pdf (accessed on 15 May 2025).
- Trajanoska, M.; Stojanov, R.; Trajanov, D. Enhancing knowledge graph construction using large language models. arXiv 2023, arXiv:2305.04676. [Google Scholar] [CrossRef] [Scilit]
- Es, S.; James, J.; Anke, L.E.; Schockaert, S. Ragas: Automated evaluation of retrieval augmented generation. In Proceedings of the the 18th Conference of the European Chapter of the Association for Computational Linguistics: System Demonstrations, St. Julian’s, Malta, 17–22 March 2024; pp. 150–158. Available online: https://aclanthology.org/2024.eacl-demo.16/ (accessed on 13 June 2025).
- Chang, Y.; Wang, X.; Wang, J.; Wu, Y.; Yang, L.; Zhu, K.; Chen, H.; Yi, X.; Wang, C.; Wang, Y.; et al. A survey on evaluation of large language models. ACM Trans. Intell. Syst. Technol. 2024, 15, 1–45. [Google Scholar] [CrossRef] [Scilit]
- Rajabi, E.; Midha, R.; de Souza, J.F. Constructing a knowledge graph for open government data: The case of Nova Scotia disease datasets. J. Biomed. Semant. 2023, 14, 4. [Google Scholar] [CrossRef] [Scilit]
- Pellegrino, M.A.; Rula, A.; Tuozzo, G. KGHeartBeat: An Open Source Tool for Periodically Evaluating the Quality of Knowledge Graphs. In Proceedings of the International Semantic Web Conference. Springer, Hanover, MD, USA, 11–15 November 2024; pp. 40–58. [Google Scholar] [CrossRef] [Scilit]
- Dong, K.; Sun, A.; Kim, J.J.; Li, X. Syntactic multi-view learning for open information extraction. arXiv 2022, arXiv:2212.02068. [Google Scholar] [CrossRef] [Scilit]
- Su, P.; Vijay-Shanker, K. Investigation of improving the pre-training and fine-tuning of BERT model for biomedical relation extraction. BMC Bioinform. 2022, 23, 120. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Robertson, S.; Zaragoza, H. The probabilistic relevance framework: BM25 and beyond. Found. Trends® Inf. Retr. 2009, 3, 333–389. [Google Scholar] [CrossRef] [Scilit]
- Alhabashneh, O.; Iqbal, R.; Doctor, F.; James, A. Fuzzy rule based profiling approach for enterprise information seeking and retrieval. Inf. Sci. 2017, 394, 18–37. [Google Scholar] [CrossRef] [Scilit]
- Guo, D.; Yang, D.; Zhang, H.; Song, J.; Zhang, R.; Xu, R.; Zhu, Q.; Ma, S.; Wang, P.; Bi, X.; et al. Deepseek-r1: Incentivizing reasoning capability in llms via reinforcement learning. arXiv 2025, arXiv:2501.12948. [Google Scholar] [CrossRef] [Scilit]
- Gharagozlou, H.; Mohammadzadeh, J.; Bastanfard, A.; Ghidary, S.S. Semantic relation extraction: A review of approaches, datasets, and evaluation methods with looking at the methods and datasets in the Persian language. ACM Trans. Asian Low-Resour. Lang. Inf. Process. 2023, 22, 1–29. [Google Scholar] [CrossRef] [Scilit]
- Liu, P.; Yuan, W.; Fu, J.; Jiang, Z.; Hayashi, H.; Neubig, G. Pre-train, prompt, and predict: A systematic survey of prompting methods in natural language processing. ACM Comput. Surv. 2023, 55, 1–35. [Google Scholar] [CrossRef] [Scilit]
- Hang, C.N.; Yu, P.D.; Tan, C.W. TrumorGPT: Graph-Based Retrieval-Augmented Large Language Model for Fact-Checking. IEEE Trans. Artif. Intell. 2025. [Google Scholar] [CrossRef] [Scilit]
- Cao, H. Recent advances in text embedding: A Comprehensive Review of Top-Performing Methods on the MTEB Benchmark. arXiv 2024, arXiv:2406.01607. [Google Scholar] [CrossRef] [Scilit]
- Pelofske, E.; Liebrock, L.M.; Urias, V. Cybersecurity threat hunting and vulnerability analysis using a Neo4j graph database of open source intelligence. arXiv 2023, arXiv:2301.12013. [Google Scholar] [CrossRef] [Scilit]
- Wang, B.; Deng, X.; Sun, H. Iteratively prompt pre-trained language models for chain of thought. arXiv 2022, arXiv:2203.08383. [Google Scholar] [CrossRef] [Scilit]
- Grattafiori, A.; Dubey, A.; Jauhri, A.; Pandey, A.; Kadian, A.; Al-Dahle, A.; Letman, A.; Mathur, A.; Schelten, A.; Vaughan, A.; et al. The llama 3 herd of models. arXiv 2024, arXiv:2407.21783. [Google Scholar] [CrossRef] [Scilit]
- Bai, J.; Bai, S.; Chu, Y.; Cui, Z.; Dang, K.; Deng, X.; Fan, Y.; Ge, W.; Han, Y.; Huang, F.; et al. Qwen Technical Report. arXiv 2023, arXiv:2309.16609. [Google Scholar] [CrossRef] [Scilit]
- Wang, B.; Zhao, H.; Zhou, H.; Song, L.; Xu, M.; Cheng, W.; Zeng, X.; Zhang, Y.; Huo, Y.; Wang, Z.; et al. Baichuan-m1: Pushing the medical capability of large language models. arXiv 2025, arXiv:2502.12671. [Google Scholar] [CrossRef] [Scilit]
- GLM, T.; Zeng, A.; Xu, B.; Wang, B.; Zhang, C.; Yin, D.; Zhang, D.; Rojas, D.; Feng, G.; Zhao, H.; et al. Chatglm: A family of large language models from glm-130b to glm-4 all tools. arXiv 2024, arXiv:2406.12793. [Google Scholar] [CrossRef] [Scilit]
- Ibtasham, M.S.; Bashir, S.; Abbas, M.; Haider, Z.; Saadatmand, M.; Cicchetti, A. ReqRAG: Enhancing Software Release Management through Retrieval-Augmented LLMs: An Industrial Study. In Proceedings of the International Working Conference on Requirements Engineering: Foundation for Software Quality; Springer: Cham, Switzerland, 2025; pp. 277–292. [Google Scholar]
- Lin, C.Y. Rouge: A package for automatic evaluation of summaries. In Proceedings of the Text Summarization Branches Out, Barcelona, Spain, 25–26 July 2004; pp. 74–81. [Google Scholar] [CrossRef] [Scilit]
- Reimers, N.; Gurevych, I. Sentence-bert: Sentence embeddings using siamese bert-networks. arXiv 2019, arXiv:1908.10084. [Google Scholar] [CrossRef] [Scilit]
- Rei, R.; Stewart, C.; Farinha, A.C.; Lavie, A. COMET: A neural framework for MT evaluation. arXiv 2020, arXiv:2009.09025. [Google Scholar] [CrossRef] [Scilit]
- Sarmah, B.; Li, M.; Lyu, J.; Frank, S.; Castellanos, N.; Pasquali, S.; Mehta, D. How to Choose a Threshold for an Evaluation Metric for Large Language Models. arXiv 2024, arXiv:2412.12148. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).