


Abstract
This study proposes a novel deep learning framework for predicting the shear capacity of slender reinforced concrete (RC) beams without shear reinforcement. The proposed approach employs convolutional neural networks and autoencoders to transform structural data into image representations, reconstruct missing data, and predict shear capacity with high accuracy. Using a dataset of 964 experimental results covering a wide range of beam characteristics, the framework achieves remarkable predictive performance. The image-based methodology enables the model to capture spatial dependencies, while the autoencoder reconstructs incomplete data with a fidelity exceeding 95%. The framework is validated against conventional methods under different data masking levels (10%, 20%, 30%). For 10% masking, the proposed method achieves R2 = 0.94, MAE = 0.05, and NSE = 0.93, significantly outperforming ACI 318 and Eurocode 2. Even with 30% masking, the framework maintains robust performance, with R2 = 0.85 and NSE = 0.81. These results highlight the scalability and reliability of the model in handling incomplete datasets, as well as its potential to advance structural engineering practice by integrating machine learning techniques with traditional design methodologies.
1. Introduction
The shear capacity of building structures is one of the core indicators for assessing their overall safety and stability, as it directly relates to the structural performance against shear under loading and the ability to prevent collapse. Among numerous structural members, reinforced concrete (RC) beams, which serve as key load-bearing components in building frames and bridge girders, play a decisive role in the overall load-bearing capacity and disaster resilience of the structure. Therefore, this study focuses on slender RC beams without shear reinforcement, with the aim of enhancing the prediction accuracy of their shear capacity through image reconstruction and deep learning techniques, and providing a new avenue for engineering assessment under incomplete data conditions.
Accurately predicting the shear capacity of reinforced concrete (RC) beams has long been a critical challenge in structural engineering [1,2]. Shear failure typically occurs suddenly, with little prior warning, and may lead to catastrophic structural collapse [3]. Such events not only pose a major threat to human safety but also result in severe economic losses, especially in large-scale infrastructure projects [4]. Despite the substantial efforts of engineers and researchers to develop predictive models for RC beams, the accurate estimation of shear capacity remains difficult due to the complexity and nonlinearity of the underlying structural behavior [5]. Historically, various empirical [6,7,8,9], analytical [10,11], and computational methods [12,13,14] have been employed to estimate the shear capacity of RC beams. Empirical approaches, such as the formulas in ACI 318 [15] and Eurocode 2 [16], rely on extensive experimental data and provide practical solutions for routine design. However, these methods often involve multiple assumptions, such as uniform material properties and simplified failure mechanisms, which may limit their accuracy for complex or unconventional structural configurations. Analytical methods based on classical mechanics, such as strut-and-tie models [17,18], offer more refined insights into load paths and failure modes, but still depend on idealized assumptions that do not always capture the full spectrum of nonlinear interactions in RC beams. Finite element methods (FEM), although sophisticated and capable of handling complex material and geometric behavior, are computationally expensive and require detailed modeling efforts, which are not always feasible for large-scale applications [19]. The prediction of shear capacity is further complicated by the large number of variables influencing beam behavior. These include material properties (e.g., concrete compressive strength and reinforcement yield strength), geometric characteristics (e.g., beam width, depth, and span), and external factors such as loading conditions and environmental effects. Each of these factors interacts in complex ways, and traditional models often struggle to account for such interactions without introducing simplifying assumptions [20]. Although FEM-based models provide a higher level of accuracy than empirical methods, they may be difficult to generalize beyond the conditions under which they were calibrated. In addition, the substantial computational resources required by FEM restrict its applicability in real-time or large-scale structural assessments.
In recent years, the rise of machine learning (ML) has opened new possibilities for predicting the shear capacity of RC beams. ML models, particularly deep learning algorithms, have achieved remarkable success in a wide range of fields, from natural language processing and image recognition to autonomous systems. In structural engineering, ML models can help overcome some limitations of traditional methods by learning directly from data, without relying on predefined physical equations or assumptions [21]. Notably, deep learning models such as convolutional neural networks (CNNs) have proven highly effective at extracting complex patterns from large datasets [22], which is particularly advantageous for structural prediction problems involving numerous interacting variables. A novel and promising approach in structural engineering is to convert numerical data into image representations and then use deep learning models to analyze and interpret these images [23]. In this study, we propose to transform the data describing the geometric and material properties of RC beams into grayscale images. In this transformation, each pixel of the image corresponds to a specific feature of the RC beam, such as beam width, depth, or material properties like concrete compressive strength. This conversion enables us to leverage the powerful image-processing capabilities of CNNs, which are highly effective in handling complex datasets and identifying intricate relationships among features. Compared with traditional numerical methods, image-based data representation offers several advantages [24]. First, it allows high-dimensional data to be represented in a more flexible and intuitive manner, which can be difficult to interpret when visualized in tabular form. Second, CNNs are particularly well suited for recognizing spatial relationships in image data, a property that is especially useful in structural engineering, where the interactions between geometric and material properties are spatially correlated. By treating structural data as images, CNNs can learn both local and global dependencies within the data, thereby enhancing their ability to accurately predict shear capacity [25].
To further improve the practicality of this approach, we introduce a new technique that simulates incomplete or missing structural data by masking certain parts of the images. In practice, structural engineers often face incomplete datasets due to missing information, inconsistent data collection, or inaccessible measurement points [26]. By simulating such conditions in the image-based data, we mask various regions of the images to represent missing structural attributes, and then apply an autoencoder-based deep learning model to reconstruct the missing parts of the images. Autoencoders are a class of neural networks that are particularly effective at learning compact and informative representations of data by encoding the input into a compressed form and then reconstructing the output. In this context, the autoencoder learns latent patterns within the data and can “fill in” missing information in the images, thereby providing a complete dataset for subsequent analysis. Once the missing parts of the images have been reconstructed, the complete images are converted back into numerical data, which are then used to predict the shear capacity of RC beams. By utilizing the reconstructed images, the model benefits from a richer and more complete dataset that incorporates information inferred by the autoencoder. This allows the model to deliver more accurate shear capacity predictions than would be possible using incomplete data alone. One of the key innovations of this study is the integration of image processing and data completion for predicting shear capacity. This approach not only improves the robustness of the model by effectively handling incomplete data, but also enables the deep learning model to capture more complex relationships within the data. Furthermore, the image-based method provides an intuitive way to visualize and interpret the data, allowing structural engineers to gain deeper insights into the relationships between different beam properties and overall structural performance. Several previous studies have explored the use of machine learning models—such as artificial neural networks (ANNs), support vector machines (SVMs), and gradient boosting algorithms—to predict the shear capacity of RC beams [27,28,29,30,31,32,33,34,35,36,37]. While these methods have been successful in certain contexts, they often rely on manual feature engineering and struggle to capture long-range dependencies among structural parameters. In contrast, the use of CNNs in this study enables automatic feature extraction and the identification of both local and global patterns in the data. In addition, the integration of autoencoder-based data reconstruction provides a principled way to handle missing data [38], further enhancing the predictive capability of the model.
This study proposes a novel approach that transforms structural data into images, processes these images to simulate and handle missing information, and employs deep learning to predict the shear capacity of slender RC beams without shear reinforcement. By leveraging the complementary strengths of CNNs and autoencoders, our goal is to overcome the limitations of traditional methods and provide a more accurate, flexible, and intuitive framework for predicting shear capacity. This image-based framework not only improves prediction accuracy but also paves the way for broader applications of deep learning in structural engineering, particularly in scenarios involving incomplete or uncertain data.
2. Materials and Methods
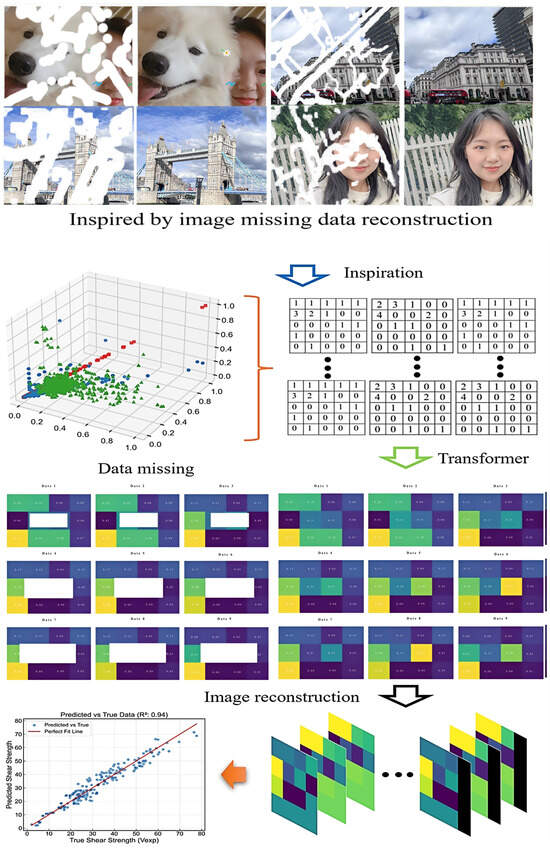
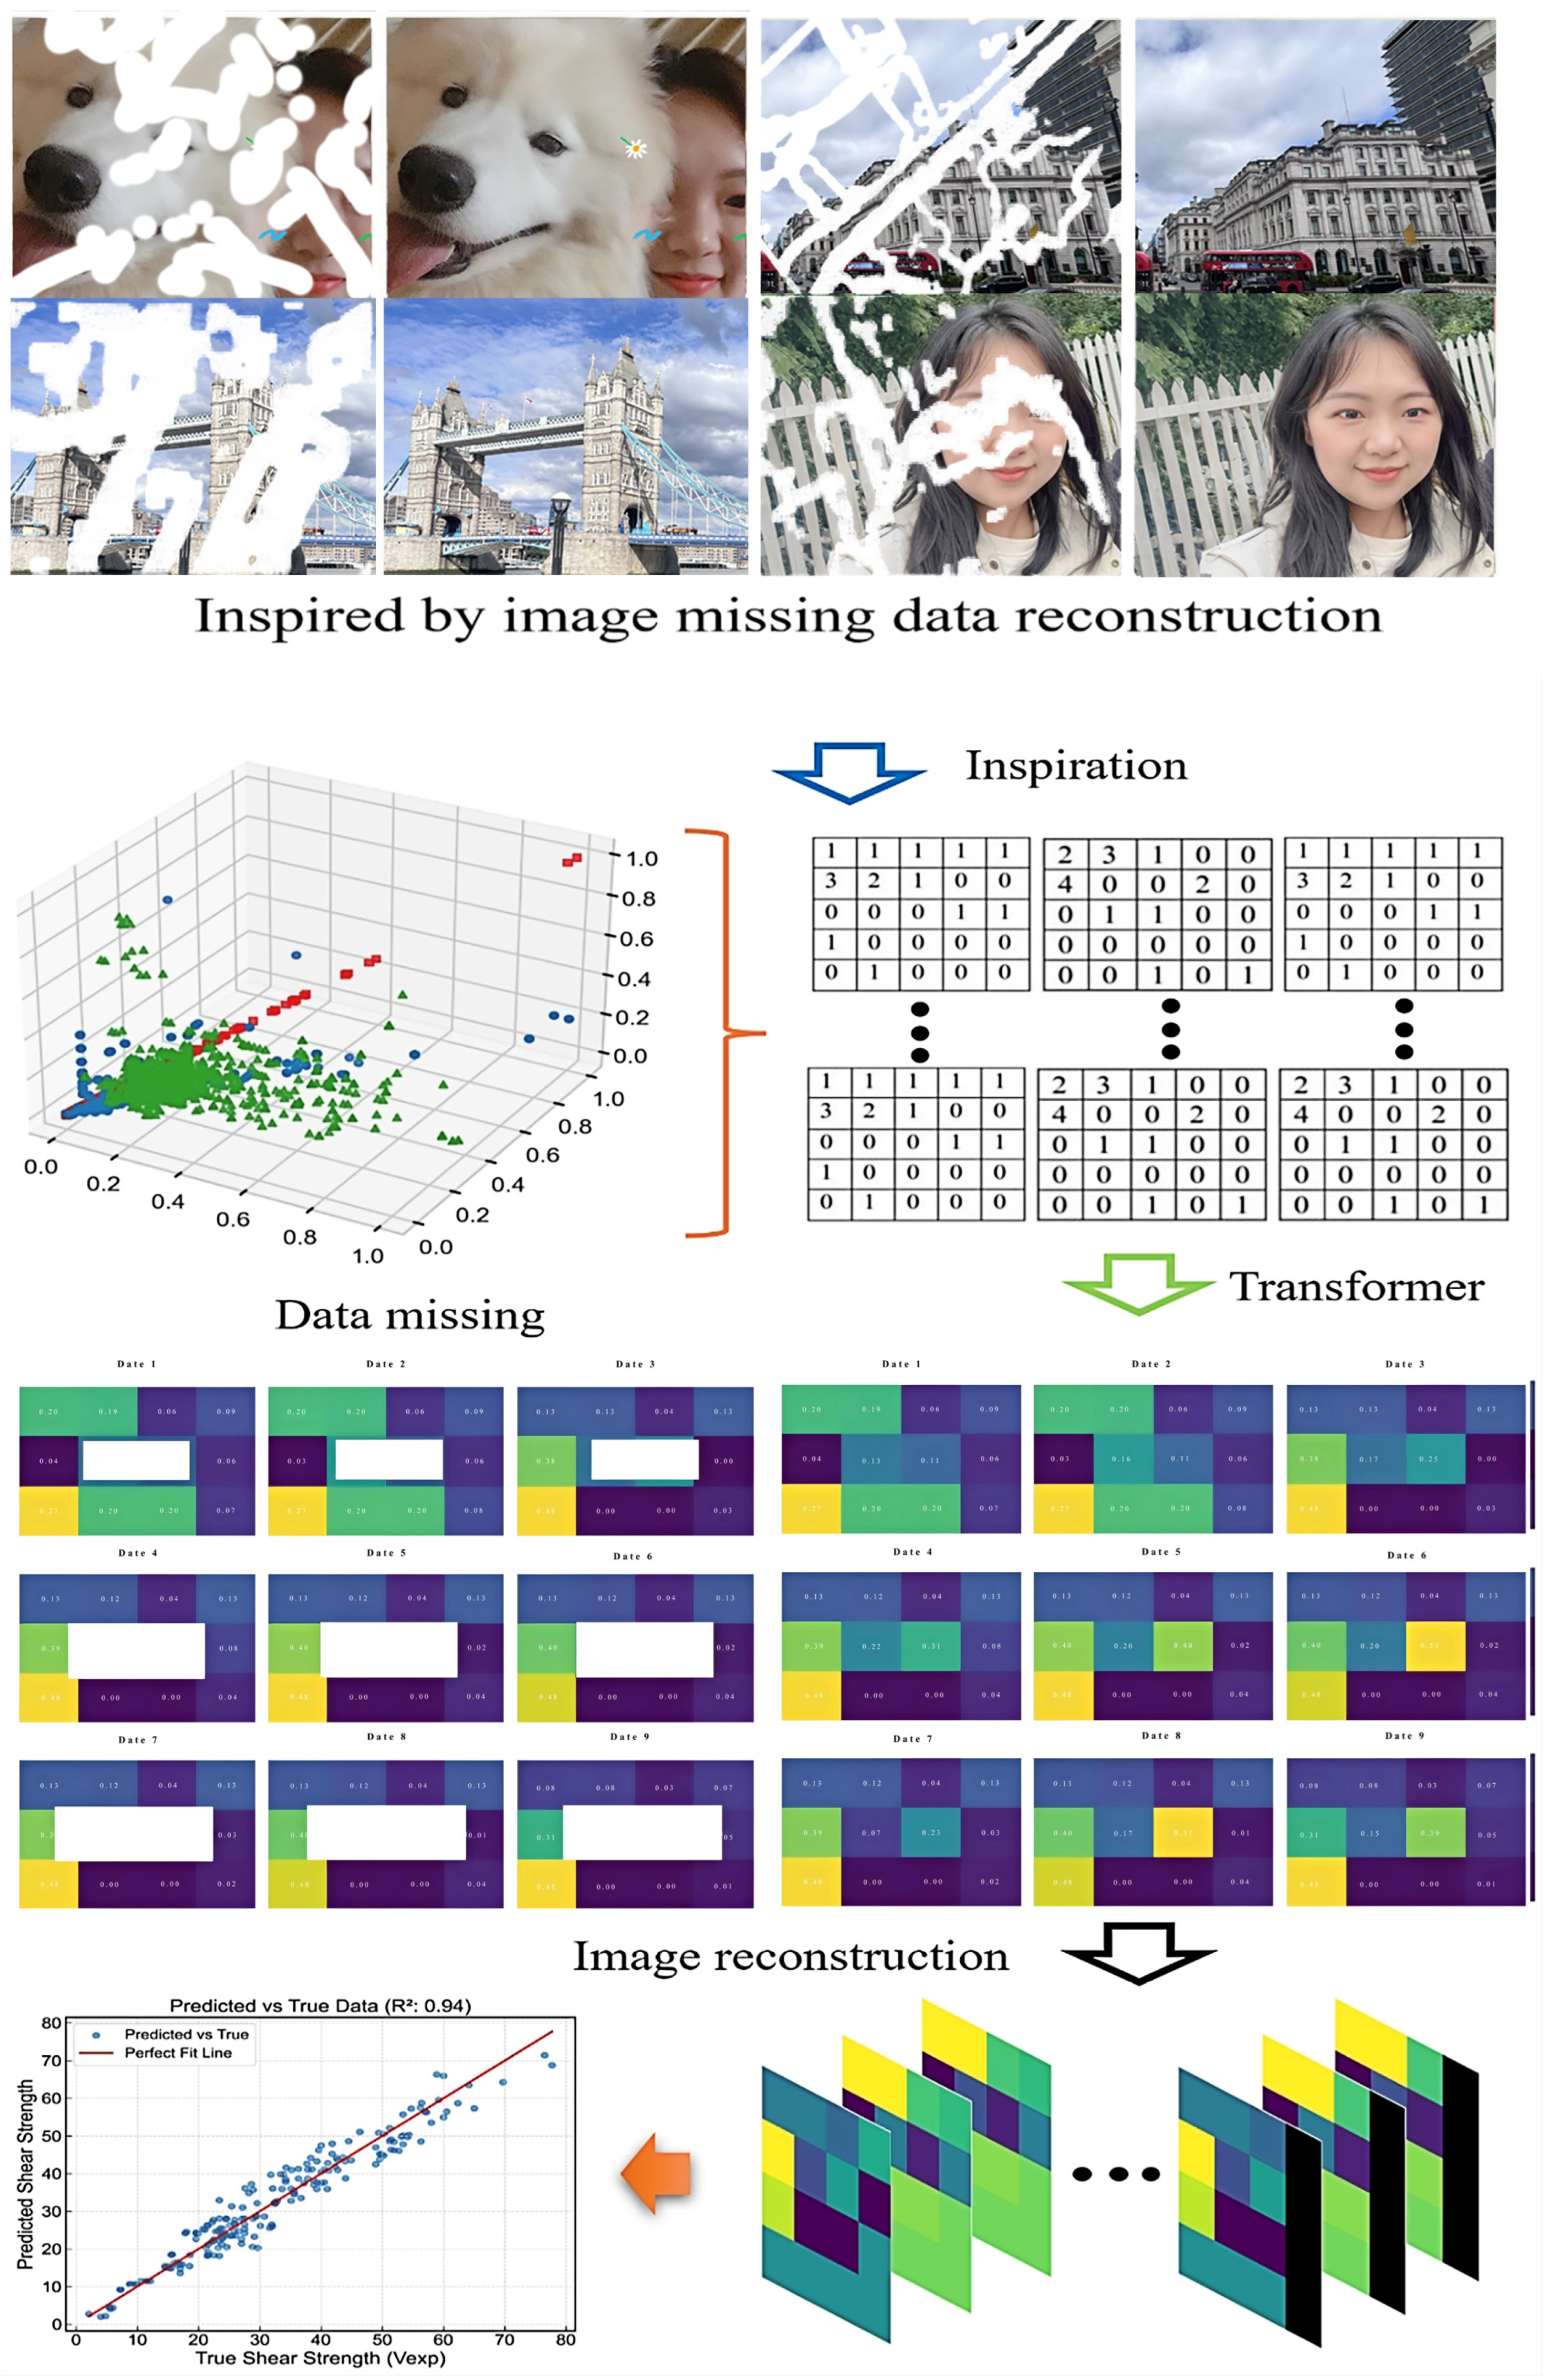
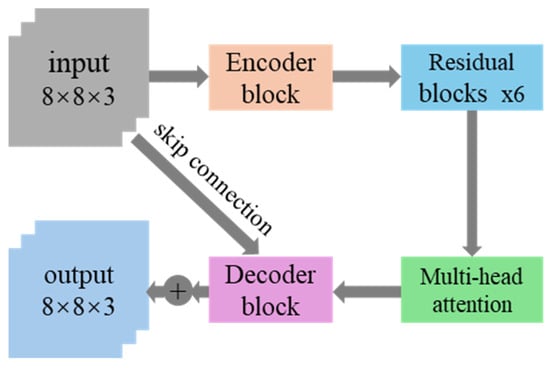
This study proposes a novel method for predicting the shear capacity of slender RC beams without shear reinforcement, as illustrated in Figure 1. Inspired by advances in the field of image processing, particularly in missing data reconstruction, the proposed method integrates innovative techniques to address the challenges posed by incomplete structural datasets. The approach transforms structural data into image representations, employs deep learning techniques to reconstruct missing data, and finally predicts the shear capacity based on the reconstructed dataset.
Figure 1.
Architecture of the proposed framework.
2.1. Data Preparation and Feature Scaling
The dataset used in this study consists of experimental data on RC beams, including geometric properties (beam width, depth, and span), material properties (concrete compressive strength and steel yield strength), and shear capacity as the target variable. To eliminate the adverse effects of differing dimensions and magnitudes on model training, all input features are standardized using the StandardScaler function in sklearn. Let xj(i) denote the j-th raw feature of the i-th sample, and let and be the mean and standard deviation of this feature in the training set, respectively. The standardized feature is then defined as
The μj and σj in the above equation are computed solely from the samples in the training set, and the same linear transformation is subsequently applied to the validation and test sets to avoid information leakage. The output target, namely the experimental shear capacity Vexp, is also standardized in the same form as in Equation (1), and its mean and standard deviation are likewise estimated only on the training set. Model training and evaluation are both conducted in the normalized space; when errors in physical units are required, the predicted results are restored to kN by inverse standardization, which is suitable for the subsequent image-based processing.
2.2. Image Representation of Data
To exploit the powerful capabilities of convolutional neural networks (CNNs) for structural prediction, the standardized data are converted into RGB images. The feature set of each beam is reshaped into a 3 × 4 matrix, where each pixel represents a specific beam characteristic. Since the dataset contains 11 features, an additional feature padded with zero is introduced to form a complete 3 × 4 grid, as follows:
where denotes the padded feature vector. This transformation enables the image-based model to analyze local and global interactions among features in a spatial format. On this basis, is first replicated three times along the channel dimension to construct an initial RGB feature map of size 3 × 4 × 3, with the three channels sharing the same grayscale intensity distribution. Using bilinear interpolation, is then uniformly rescaled to an 8 × 8 × 3 input image, that is, an 8 × 8 RGB image obtained from the 11 standardized features through zero padding, 3 × 4 grid rearrangement, and bilinear interpolation.
2.3. Image Masking for Simulating Missing Data
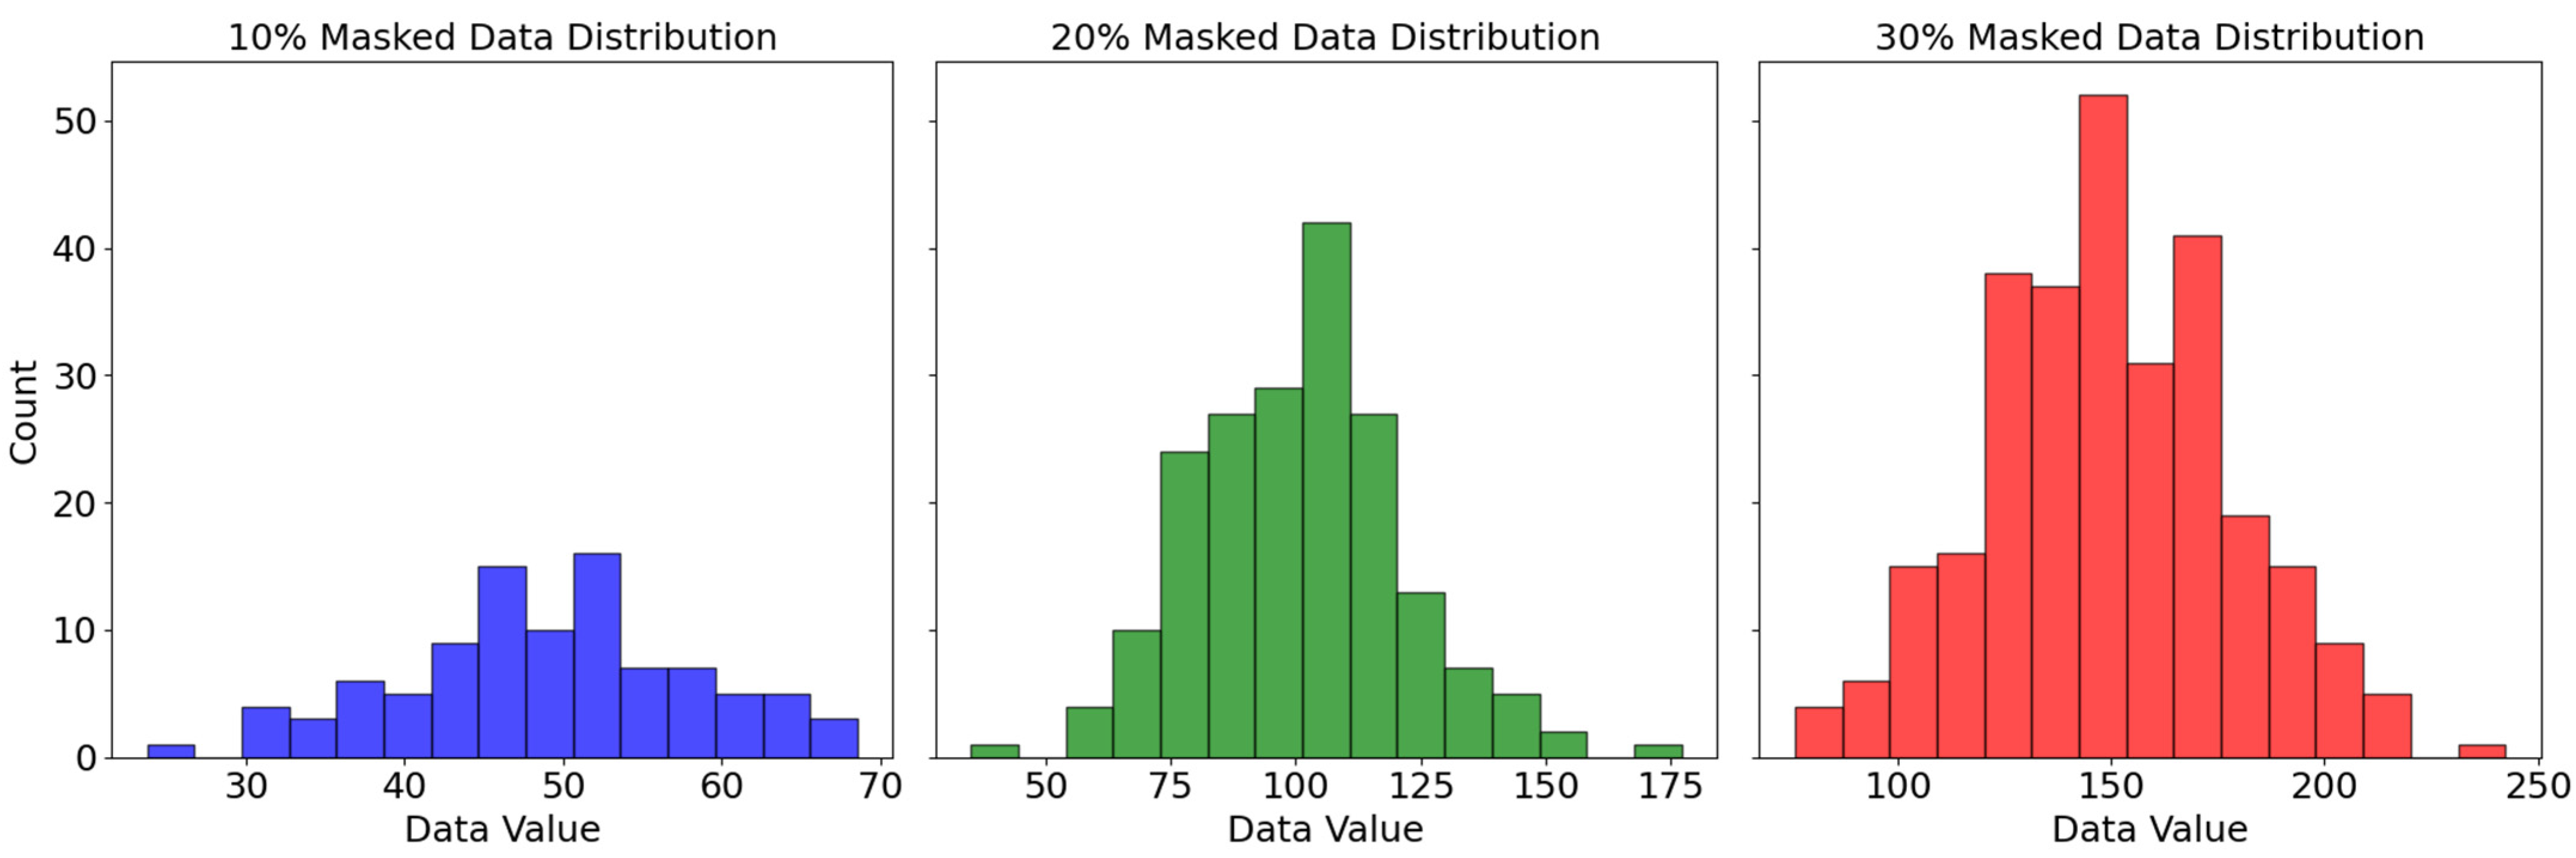
In order to simulate practical engineering scenarios in which some structural parameters are missing or incompletely recorded, this study introduces a controllable masking operator on the basis of the image representation to impose an “artificial missingness” on the input images. Different from earlier schemes that simply masked the right half of the image, the final approach adopted in this paper is a random masking strategy controlled by the proportion of missing features, and three missing levels of 10%, 20% and 30% are considered in the numerical analysis.
where (i, j) denotes the pixel coordinates of the image. Masking is performed at the level of feature blocks, that is, once a certain structural feature is regarded as missing, all its corresponding pixels (in all channels) in the image are set to zero, while the regions corresponding to the remaining features remain unchanged. In this way, the performance variation in the proposed reconstruction–prediction framework under different missing levels such as 10%, 20%, and 30% can be systematically evaluated, rather than being limited to a single 50% masking case.
2.4. Autoencoder for Image Reconstruction
This study employs an autoencoder to reconstruct the masked regions of the images. The autoencoder consists of two main components: an encoder, which compresses the input into a latent-space representation, and a decoder, which reconstructs the input from the latent space. It is composed of multiple convolutional layers, residual blocks, and multi-head attention modules, designed to simultaneously capture local spatial correlations and long-range dependencies, thereby enabling effective feature recovery even under high missing rates.
The autoencoder is trained by minimizing the mean squared error (MSE) between the original images and the reconstructed images. The loss function used to train the autoencoder is given by
where (n) is the number of pixels, and Xoriginal and Xreconstructed are the original and reconstructed images, respectively. The encoder and decoder consist of multiple convolutional layers designed to learn spatial dependencies and reconstruct the missing parts of the images. Dropout and batch normalization are applied to prevent overfitting and stabilize the training process.
2.5. Training the Autoencoder
The autoencoder is trained using the masked images as input and the original images as output. The Adam optimizer is employed for efficient gradient descent, with a learning rate scheduler that reduces the learning rate when the validation loss plateaus. Early stopping is used to prevent overfitting, and training is terminated once the validation loss ceases to improve. The learning rate update rule is given by
where α is the learning rate, and the factor is typically set to 0.2. This dynamic adjustment helps the model converge effectively without overshooting the optimal solution.
2.6. Conversion of Reconstructed Images to Numerical Data
Once the autoencoder has successfully reconstructed the missing parts of the images, the output is converted back into numerical form for further analysis. The conversion process involves flattening the reconstructed image and removing the padded feature to obtain the original 11 features, as follows:
This step restores the dataset to its original feature representation, with the additional benefit that previously missing data have been reconstructed by the autoencoder.
3. Database
3.1. Data Sources and Feature Statistics
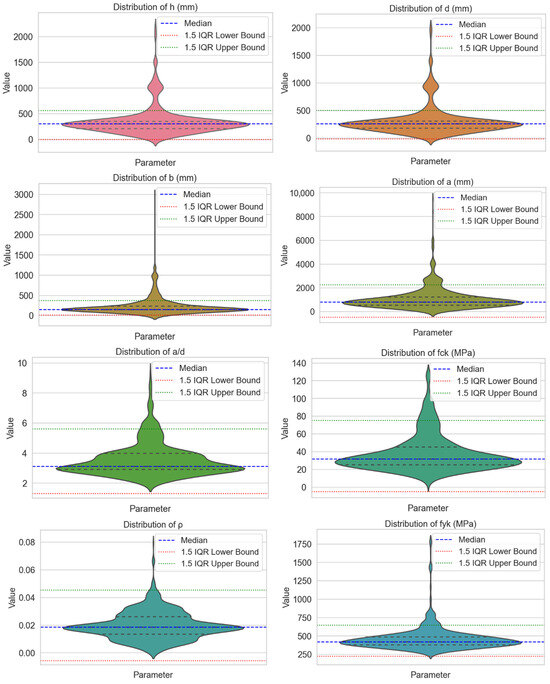
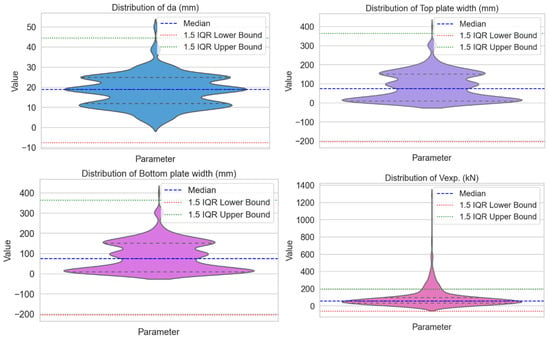
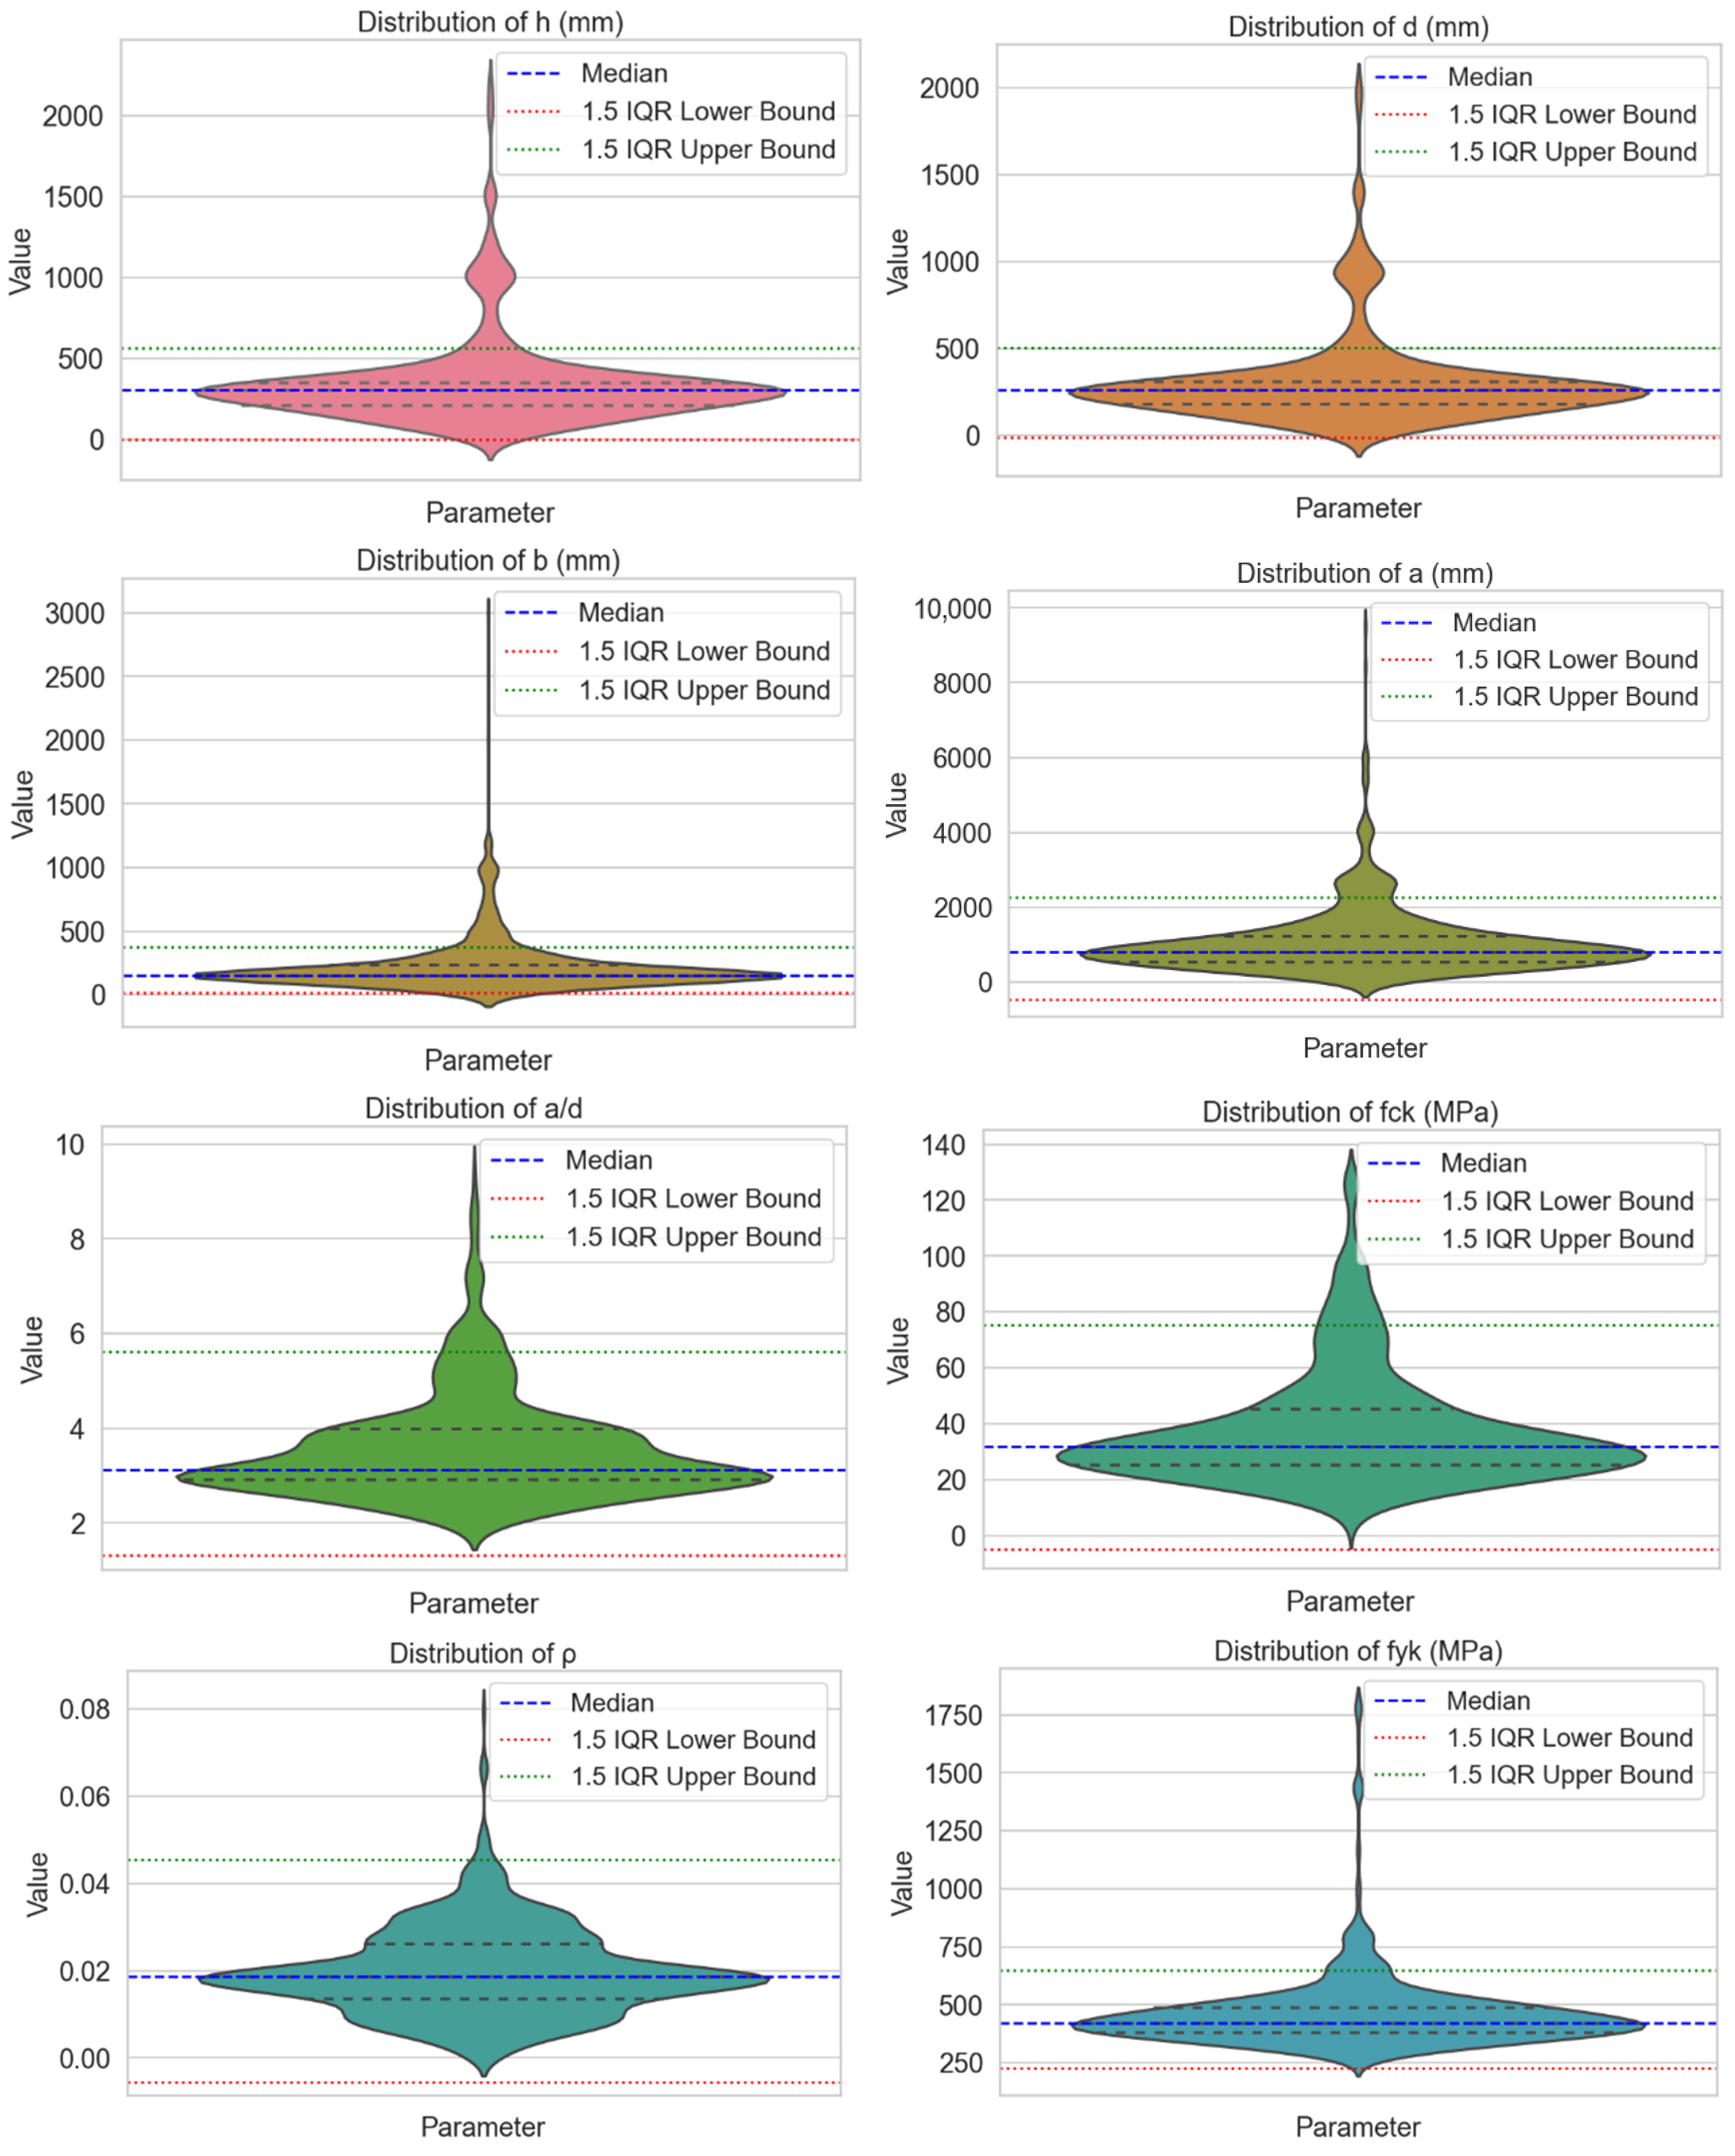
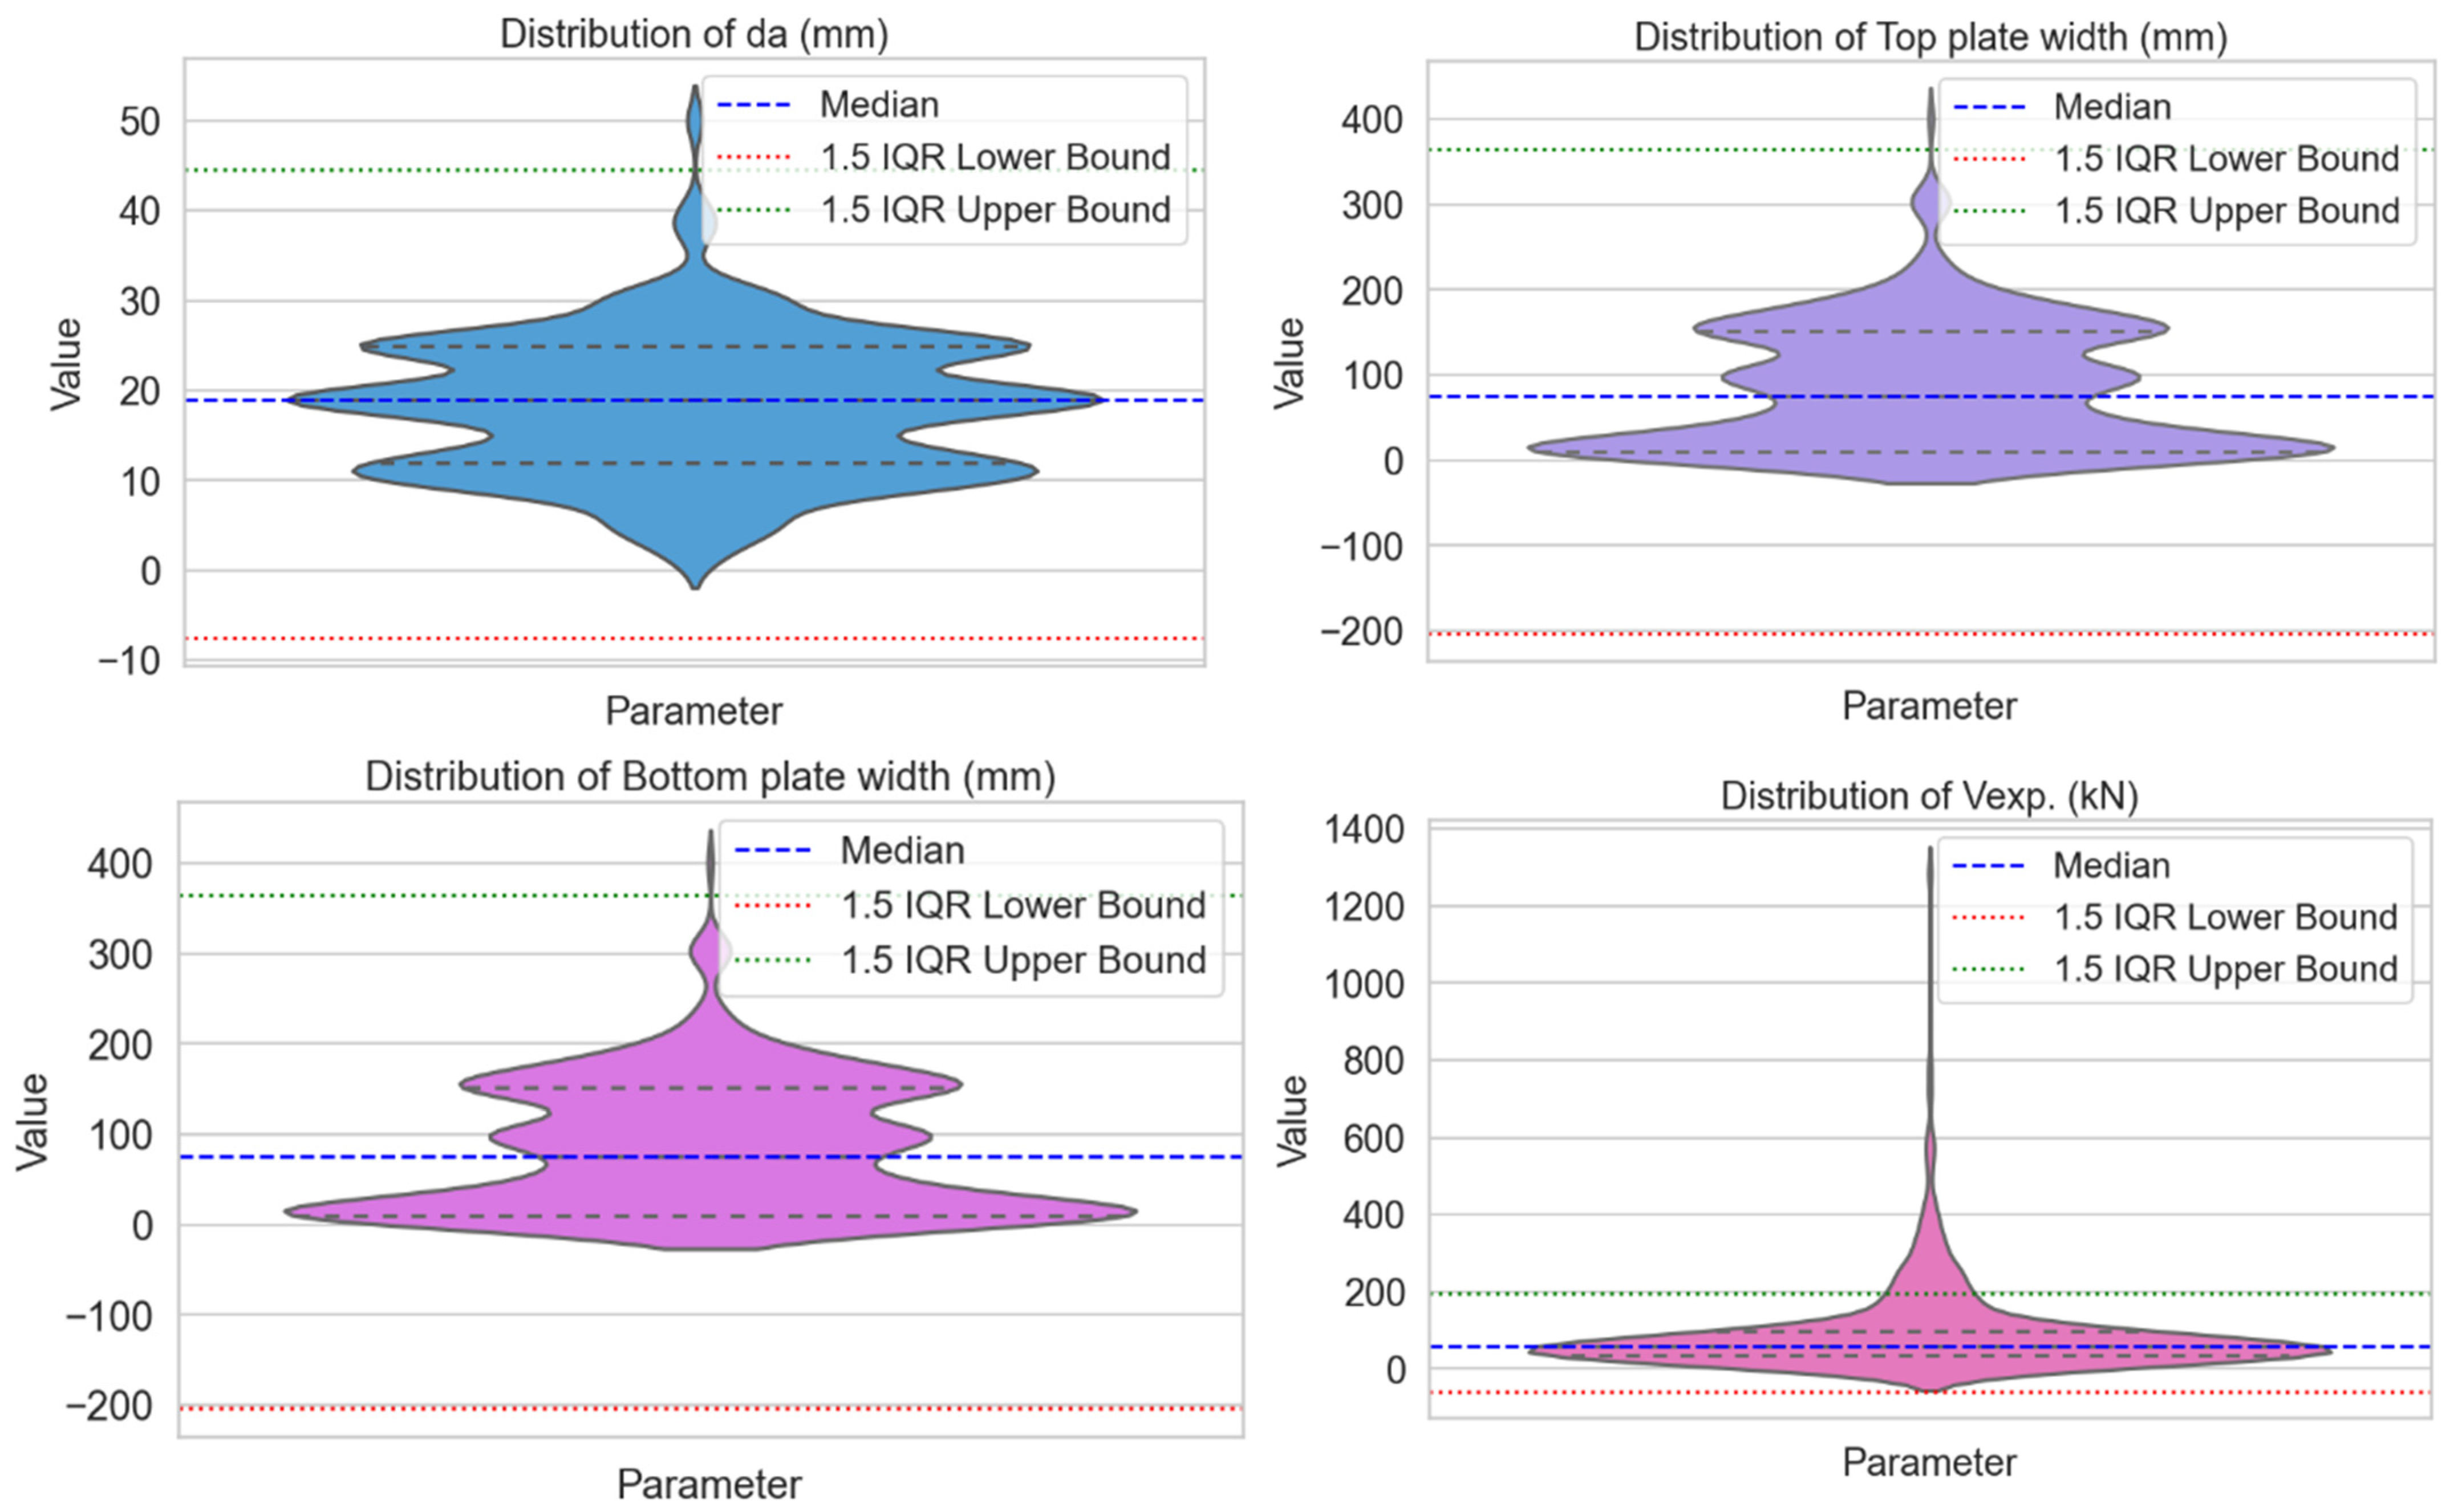
The dataset used in this study is compiled from a large number of published investigations conducted over the past sixty years. The database consists of 964 experimental results collected from nearly 80 different studies [39], providing a comprehensive basis for developing machine learning models to estimate the shear strength of slender beams without shear reinforcement. Figure 2 illustrates in detail the distributions of the input variables and the output shear strength.
Figure 2.
Distribution of input variable and output shear strength.
As shown in Figure 2, the overall depth (h) ranges from 250 mm to 2200 mm, with a mean of 305 mm and a standard deviation of 302.1 mm. It is noteworthy that most specimens have (h) values concentrated in the range of 250 mm–400 mm, while only a small number of deep-beam specimens exhibit (h > 1500) mm. The beam width varies between 20 mm and 600 mm, with a mean of 152 mm and a standard deviation of 78.3 mm. The majority of samples fall within 120 mm–200 mm, indicating that beam widths are generally concentrated in this range. A small number of data points lie below 100 mm, representing relatively narrow sections.
The concrete compressive strength ranges from 15 MPa to 120 MPa, with a mean of 42.5 MPa and a standard deviation of 18.4 MPa. Approximately 70% of the data points fall within 30 MPa–50 MPa, indicating that the dataset is concentrated around strength grades typically used in engineering practice. The longitudinal reinforcement ratio ranges from 0.2% to 5.0%, with a mean of 1.2% and a standard deviation of 0.9%. Most data points (about 75%) are concentrated between 0.8% and 1.5%, suggesting that this is a commonly adopted reinforcement ratio in structural design. The shear span-to-depth ratio ranges from 1.0 to 8.0, with a mean of 3.5 and a standard deviation of 1.4. More than 60% of the data points lie between 2.5 and 4.0, indicating that experimental studies tend to focus on conditions with moderate shear span-to-depth ratios. The experimentally measured shear strength (Vexp) varies from 5 kN to 1500 kN, with a mean of 220 kN and a standard deviation of 180 kN. Approximately 65% of the specimens have shear capacities between 100 kN and 300 kN, representing typical structural components tested in experimental studies. Through the distribution plots of each variable in Figure 2, the ranges and concentration intervals of the database in terms of geometric dimensions, material strengths, and shear capacity can be visually observed, providing insight into the representativeness and coverage of the dataset.
3.2. Analysis of Parameter Correlations
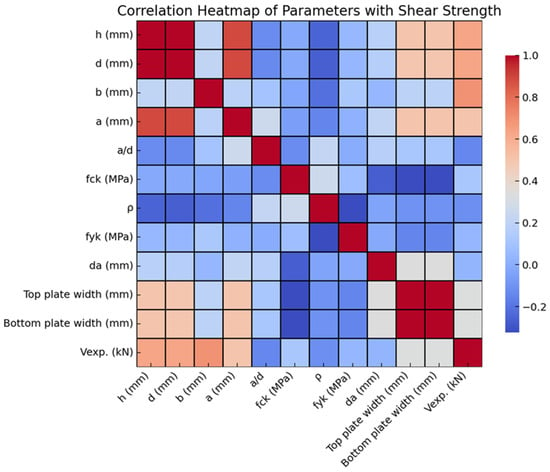
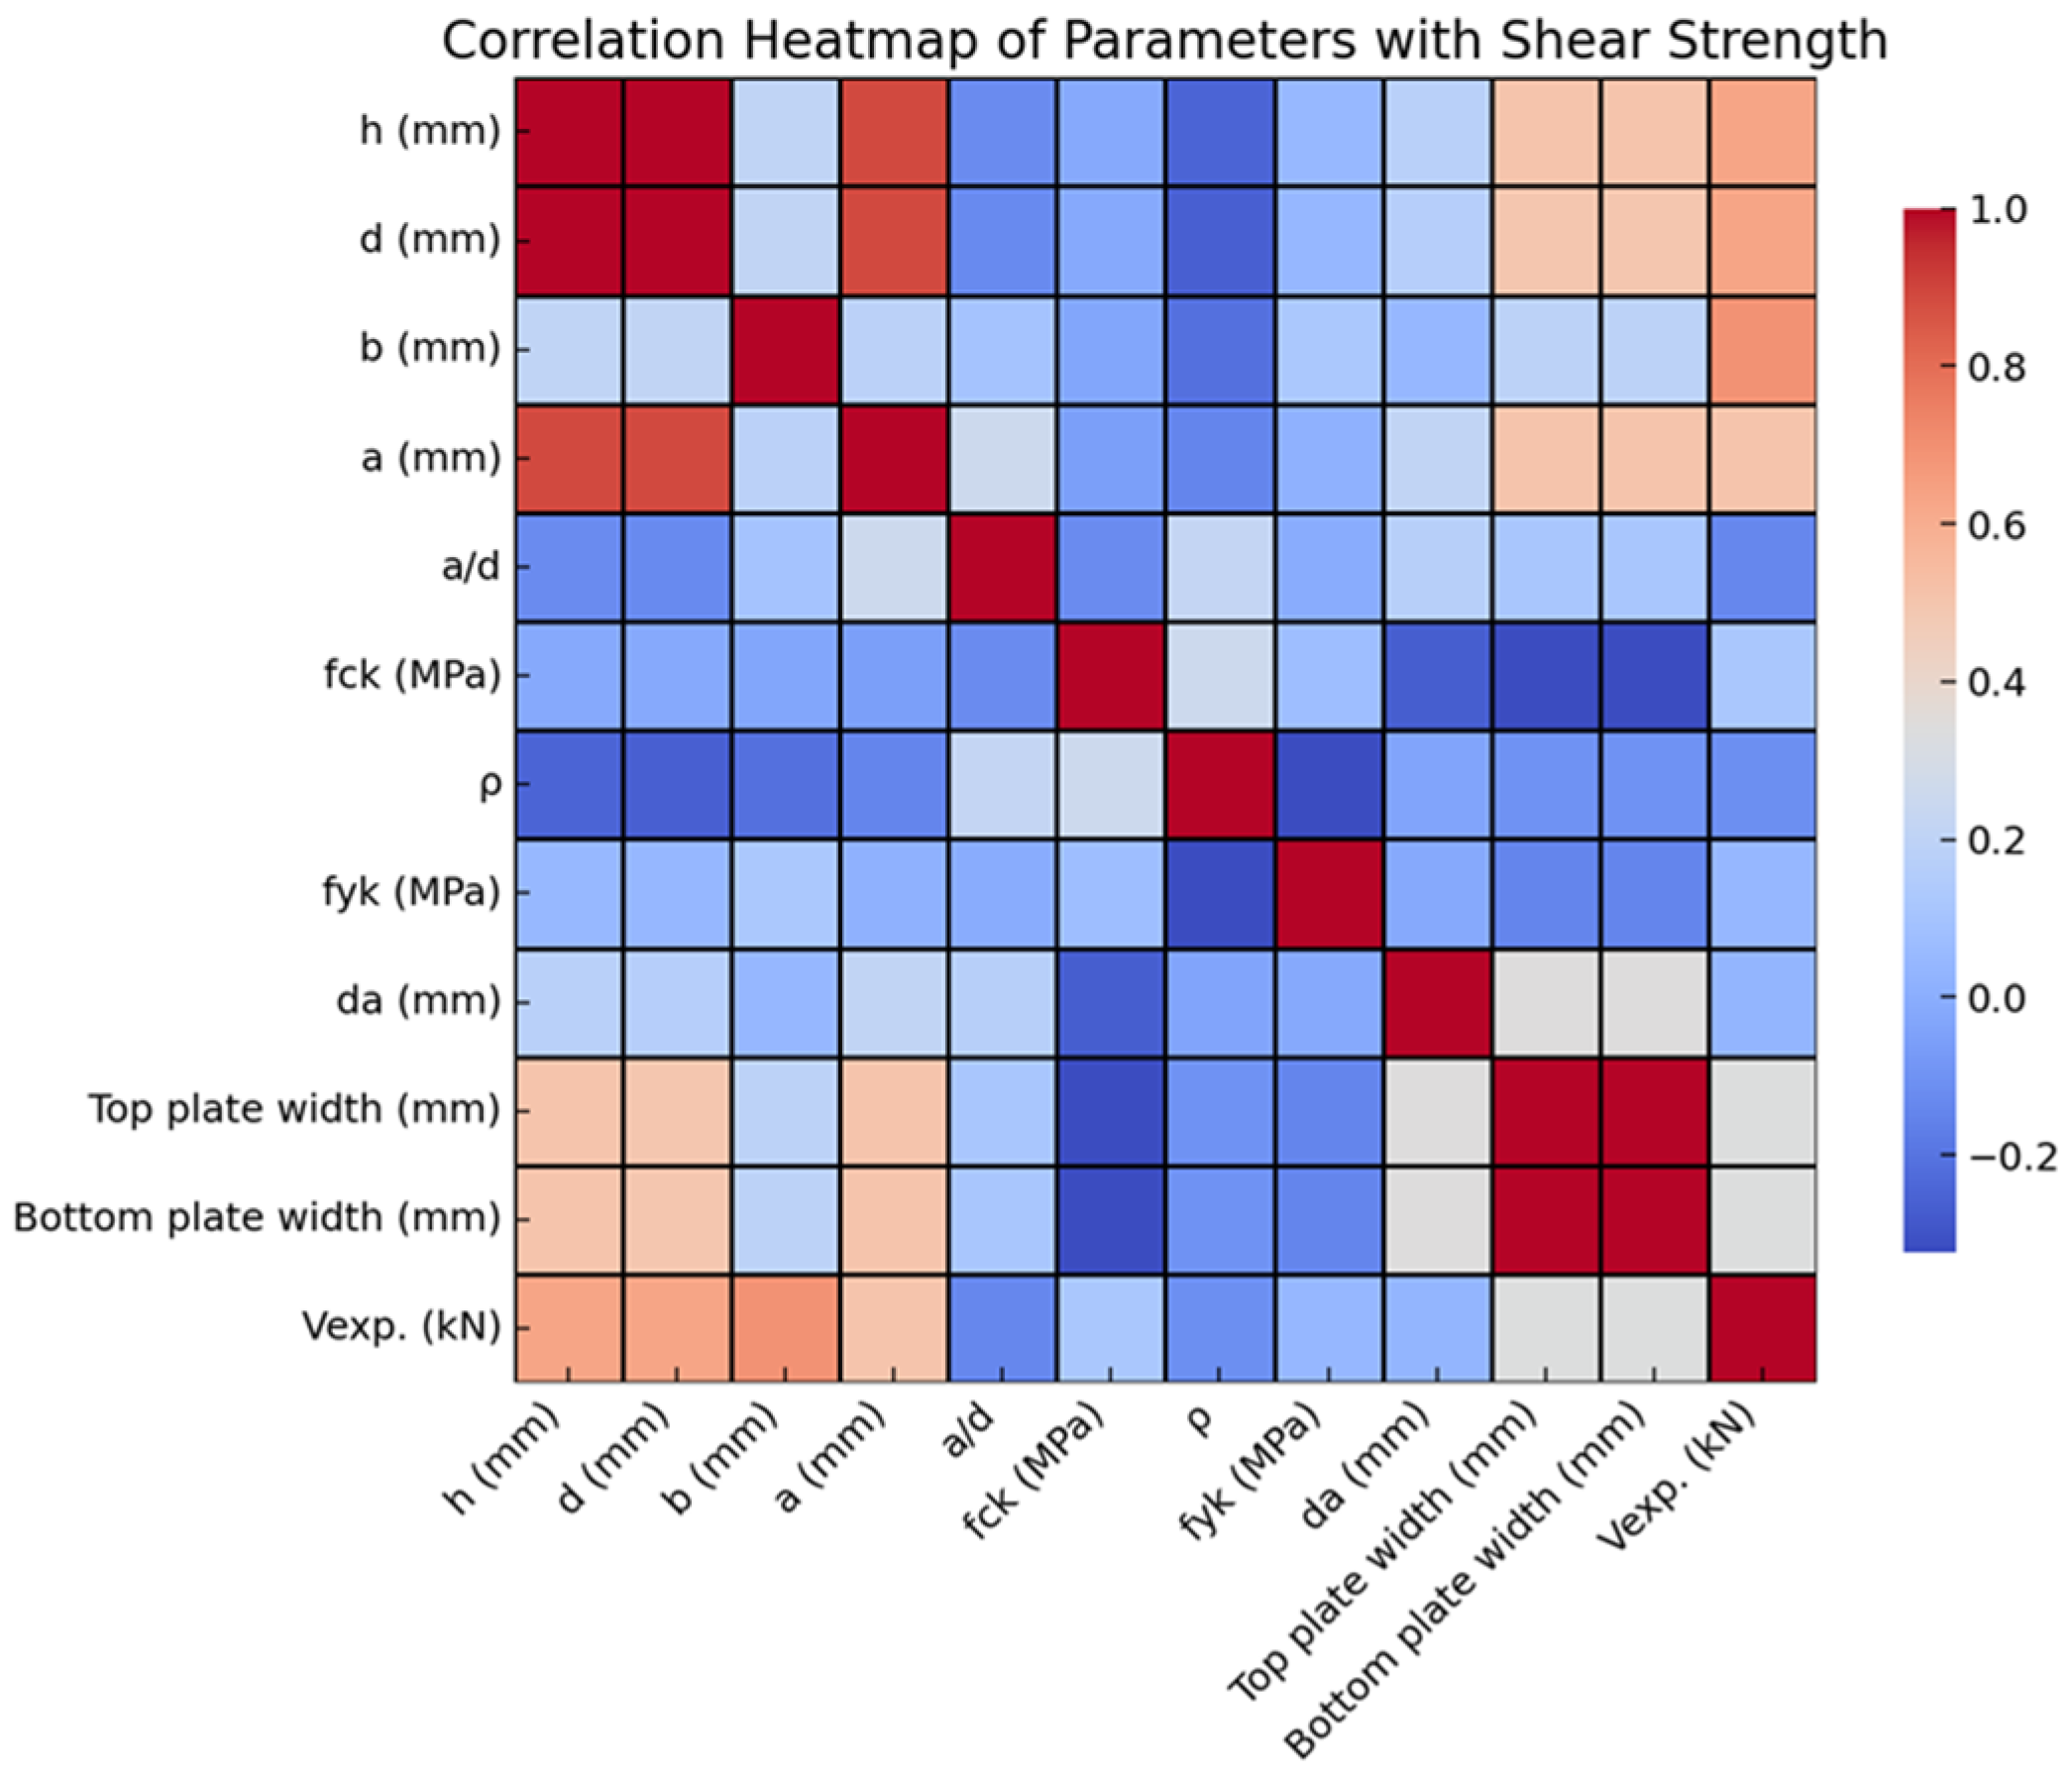
The correlations among the input parameters, as well as the relationships between the input parameters and the output parameter, are key aspects for assessing the importance and relevance of the input variables. Figure 3 presents the correlation coefficients between each pair of parameters through color intensity and numerical labels, using a heatmap to reinforce the visual expression of the relationships between the input variables and the shear capacity, thereby helping to identify the controlling parameters that have a more significant influence on Vexp. As can be seen from Figure 3, most input parameters exhibit moderate correlations with the output shear strength Vexp. For example, the depth h and width (b) show positive correlations of 0.45 and 0.38 with Vexp, respectively, indicating that, under otherwise identical conditions, increasing these parameters generally leads to higher shear strength. On the other hand, the shear span-to-depth ratio a/d has a correlation of −0.41 with Vexp, suggesting that a higher a/d ratio tends to reduce the shear capacity. Taking into account both the correlation coefficients and the scatter distributions, it can be concluded that depth h, width b, concrete compressive strength, longitudinal reinforcement ratio, and shear span ratio a/d constitute the group of parameters that most significantly affect shear capacity, among which h, b, concrete compressive strength, and longitudinal reinforcement ratio exert positive effects on shear capacity, while a/d has a clearly negative influence; the effects of the other parameters are relatively secondary. The above correlation analysis provides a statistical basis for judging the importance of each input parameter and for interpreting the results in the subsequent modeling.
Figure 3.
Correlation heatmap between parameters and shear strength.
3.3. Dataset Partitioning and Validation Strategy
To ensure the objectivity and generalizability of the model evaluation, this study performed a rigorous dataset partitioning and data-leakage prevention design before constructing the deep learning framework for the 964 experimental specimens. First, all specimens were grouped by experimental program, so that beam tests conducted within the same test campaign were assigned to the same data group. This treatment takes into account that specimens from the same experimental program often share strong consistency in terms of material properties, ranges of geometric parameters, and loading conditions; if specimens from the same program were split between the training and test sets, potential data leakage could easily occur.
After grouping, approximately 80% of the data groups were randomly assigned to a development set, and the remaining 20% were used as an independent test set for final performance evaluation. Within the development set, a group-based 5-fold cross-validation was adopted. In each fold, about 80% of the data groups were used as a training subset and the remaining 20% as a validation subset, while ensuring that specimens from the same experimental program were never split across different subsets. This “group-wise folding by test program” strategy more realistically simulates the practical engineering scenario of applying a trained model to entirely new projects.
All preprocessing operations were carried out under the premise of preventing data leakage. Specifically, the StandardScaler was fitted only on the training subset of each fold, and the resulting means and standard deviations were then applied to the corresponding validation subset and independent test set. The train–validation–test partition was first completed on the original, unmasked data, after which different masking ratios of 10%, 20%, and 30% were applied separately within each subset to simulate missing-information scenarios. This workflow ensures that specimens in the test set never participate in parameter estimation or hyperparameter tuning at any stage, fundamentally avoiding implicit data leakage introduced by preprocessing or masking operations.
Comparative analyses of the marginal distributions of key input parameters (such as beam depth, beam width, concrete compressive strength, reinforcement ratio, and shear span ratio) between the development set and the independent test set show good consistency in their statistical characteristics, indicating that the independent test set is comparable to the development set in terms of ranges of geometric and material properties. The final model hyperparameters were determined based on the average performance over 5-fold cross-validation on the development set.
4. Numerical Simulation
4.1. Deep Learning Framework
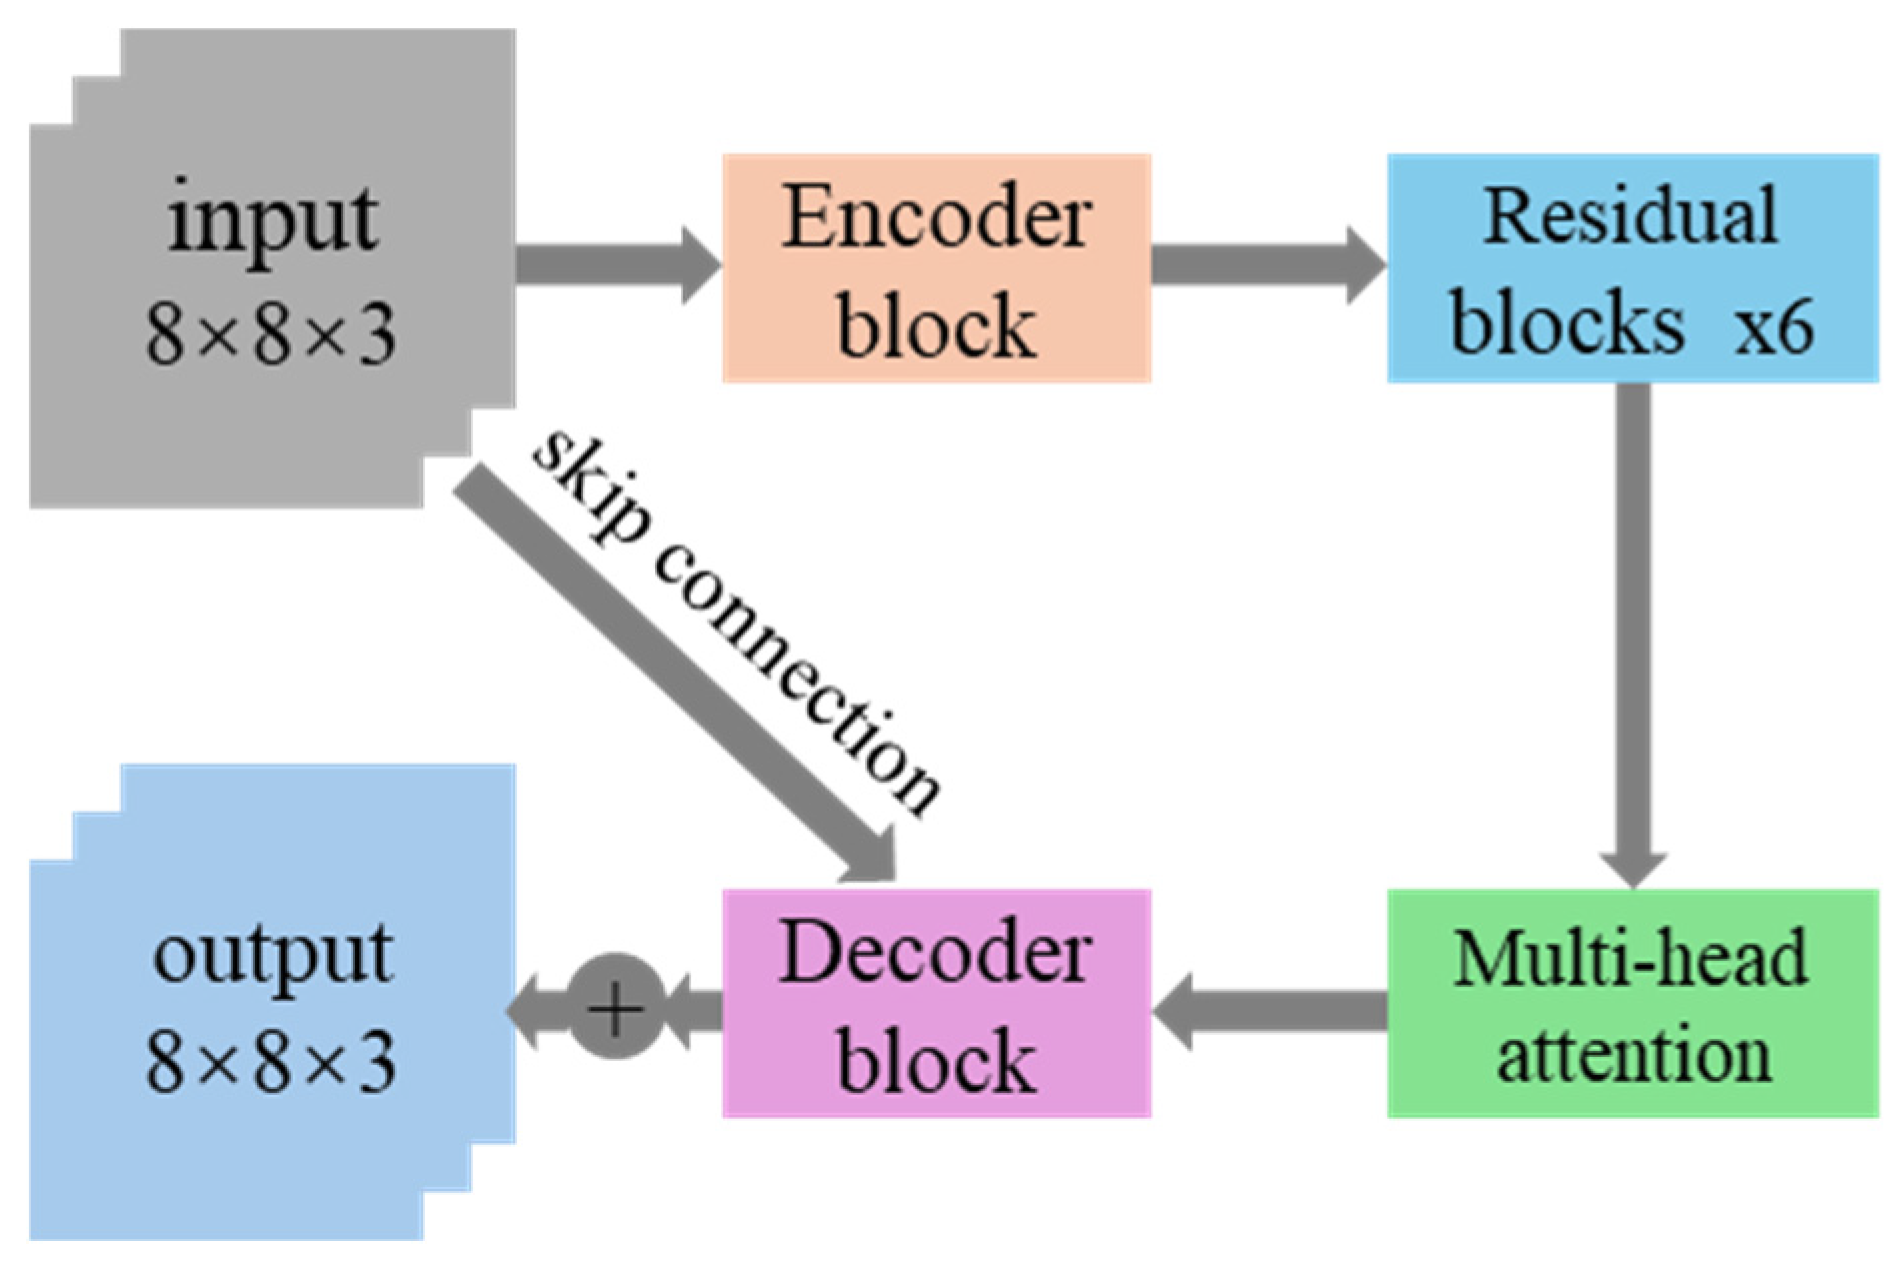
In this study, a deep learning-based framework is developed to predict the shear capacity of reinforced concrete beams, as detailed in Figure 4. The framework leverages an enhanced fully convolutional network (FCN) to reconstruct masked input features from the dataset, which is represented in an image format. The deep learning framework involves multiple advanced components, such as residual blocks, attention mechanisms, and skip connections, that improve the model’s capability to accurately predict the missing parts of the data and enhance feature extraction:
Figure 4.
The proposed deep learning framework.
- (1)
- Input layer: The input to the network is an 8 × 8 RGB image, which is obtained from the padded and reshaped feature vector of the dataset. Each image represents different physical properties of a reinforced concrete beam. The input shape is (8, 8, 3), corresponding to the grid size and the three RGB channels.
- (2)
- Initial convolutional block: The network starts with an initial convolutional block consisting of a convolutional layer with a filter size of 3 × 3, and the number of filters (num_filters) tuned as a hyperparameter in the range [128, 256, 512]. This block also includes batch normalization and a LeakyReLU activation function, which help the model capture basic spatial relationships. The output shape of this layer is (8, 8, num_filters).
- (3)
- Residual blocks with attention mechanism: The network contains [5,10] residual blocks, depending on the selected hyperparameters. Each residual block consists of two convolutional layers (each with a 3 × 3 filter size), batch normalization, a LeakyReLU activation function, and dropout to prevent overfitting. A skip connection is included within each residual block to add the original input back to the output, which helps the model retain low-level information. The output shape of each residual block is (8, 8, num_filters). To capture long-range dependencies among features, the framework also includes a multi-head attention layer. This layer is designed to learn which features should be emphasized for accurate reconstruction. The number of attention heads (attention_heads) is chosen from [8, 16, 32], and an Add layer is used to merge the attention output with the residual block output. Layer normalization is then applied to stabilize the learning process.
- (4)
- Reconstruction block: The reconstruction block consists of additional convolutional layers to improve the accuracy of the reconstructed features. The first convolutional layer uses the same number of filters (num_filters) as in the preceding blocks, followed by batch normalization, LeakyReLU activation, and a dropout rate of 0.4. The second convolutional layer uses a single filter to match the number of input channels and employs a Sigmoid activation function to ensure that the output values lie within [0, 1]. The output shape is (8, 8, 3).
- (5)
- Skip connection from input to output: To preserve the original input information, the network includes a skip connection directly from the input layer to the output layer, adding the original input back to the reconstructed output.
In the proposed framework, the total depth of the network varies with the number of residual blocks and the number of convolutional channels, and generally includes 13–23 convolutional layers. Under the optimal hyperparameter configuration finally adopted in this study (i.e., 256 convolutional filters, 6 residual blocks, and 8 attention heads), the network contains a total of 19 convolutional layers and approximately (2.1 × 10⁶) trainable parameters. On the one hand, this model capacity is sufficient to characterize the local and global spatial correlations in the masked images, enabling feature reconstruction and shear capacity regression; on the other hand, under multiple regularization measures such as batch normalization, dropout, weight decay, early stopping, and group-wise cross-validation based on test programs, the risk of overfitting is effectively controlled. It should be noted that although the original input consists of only 11 structural features, after encoding into 8 × 8 × 3 images, the learning target of the network is no longer a single feature value, but its neighborhood patterns and long-range dependencies in the spatial mapping. Under conditions of high missing rates and heterogeneity across multiple literature sources, a certain scale of convolution–residual–attention combination is still required to ensure reconstruction and prediction accuracy. Numerical results show that when the number of channels or residual blocks is further reduced, both the reconstruction SSIM and the shear capacity (R2) exhibit a significant decline, indicating that the current parameter scale achieves a relatively reasonable balance between model complexity and generalization performance.
4.2. Hyperparameter Optimization
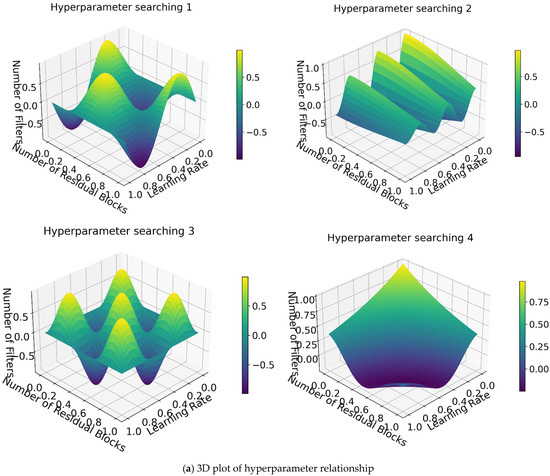
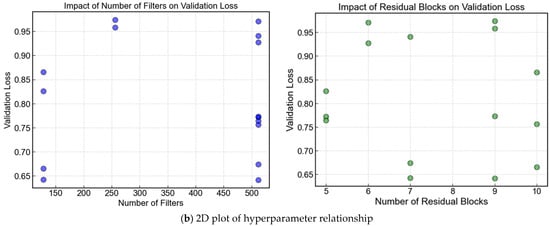
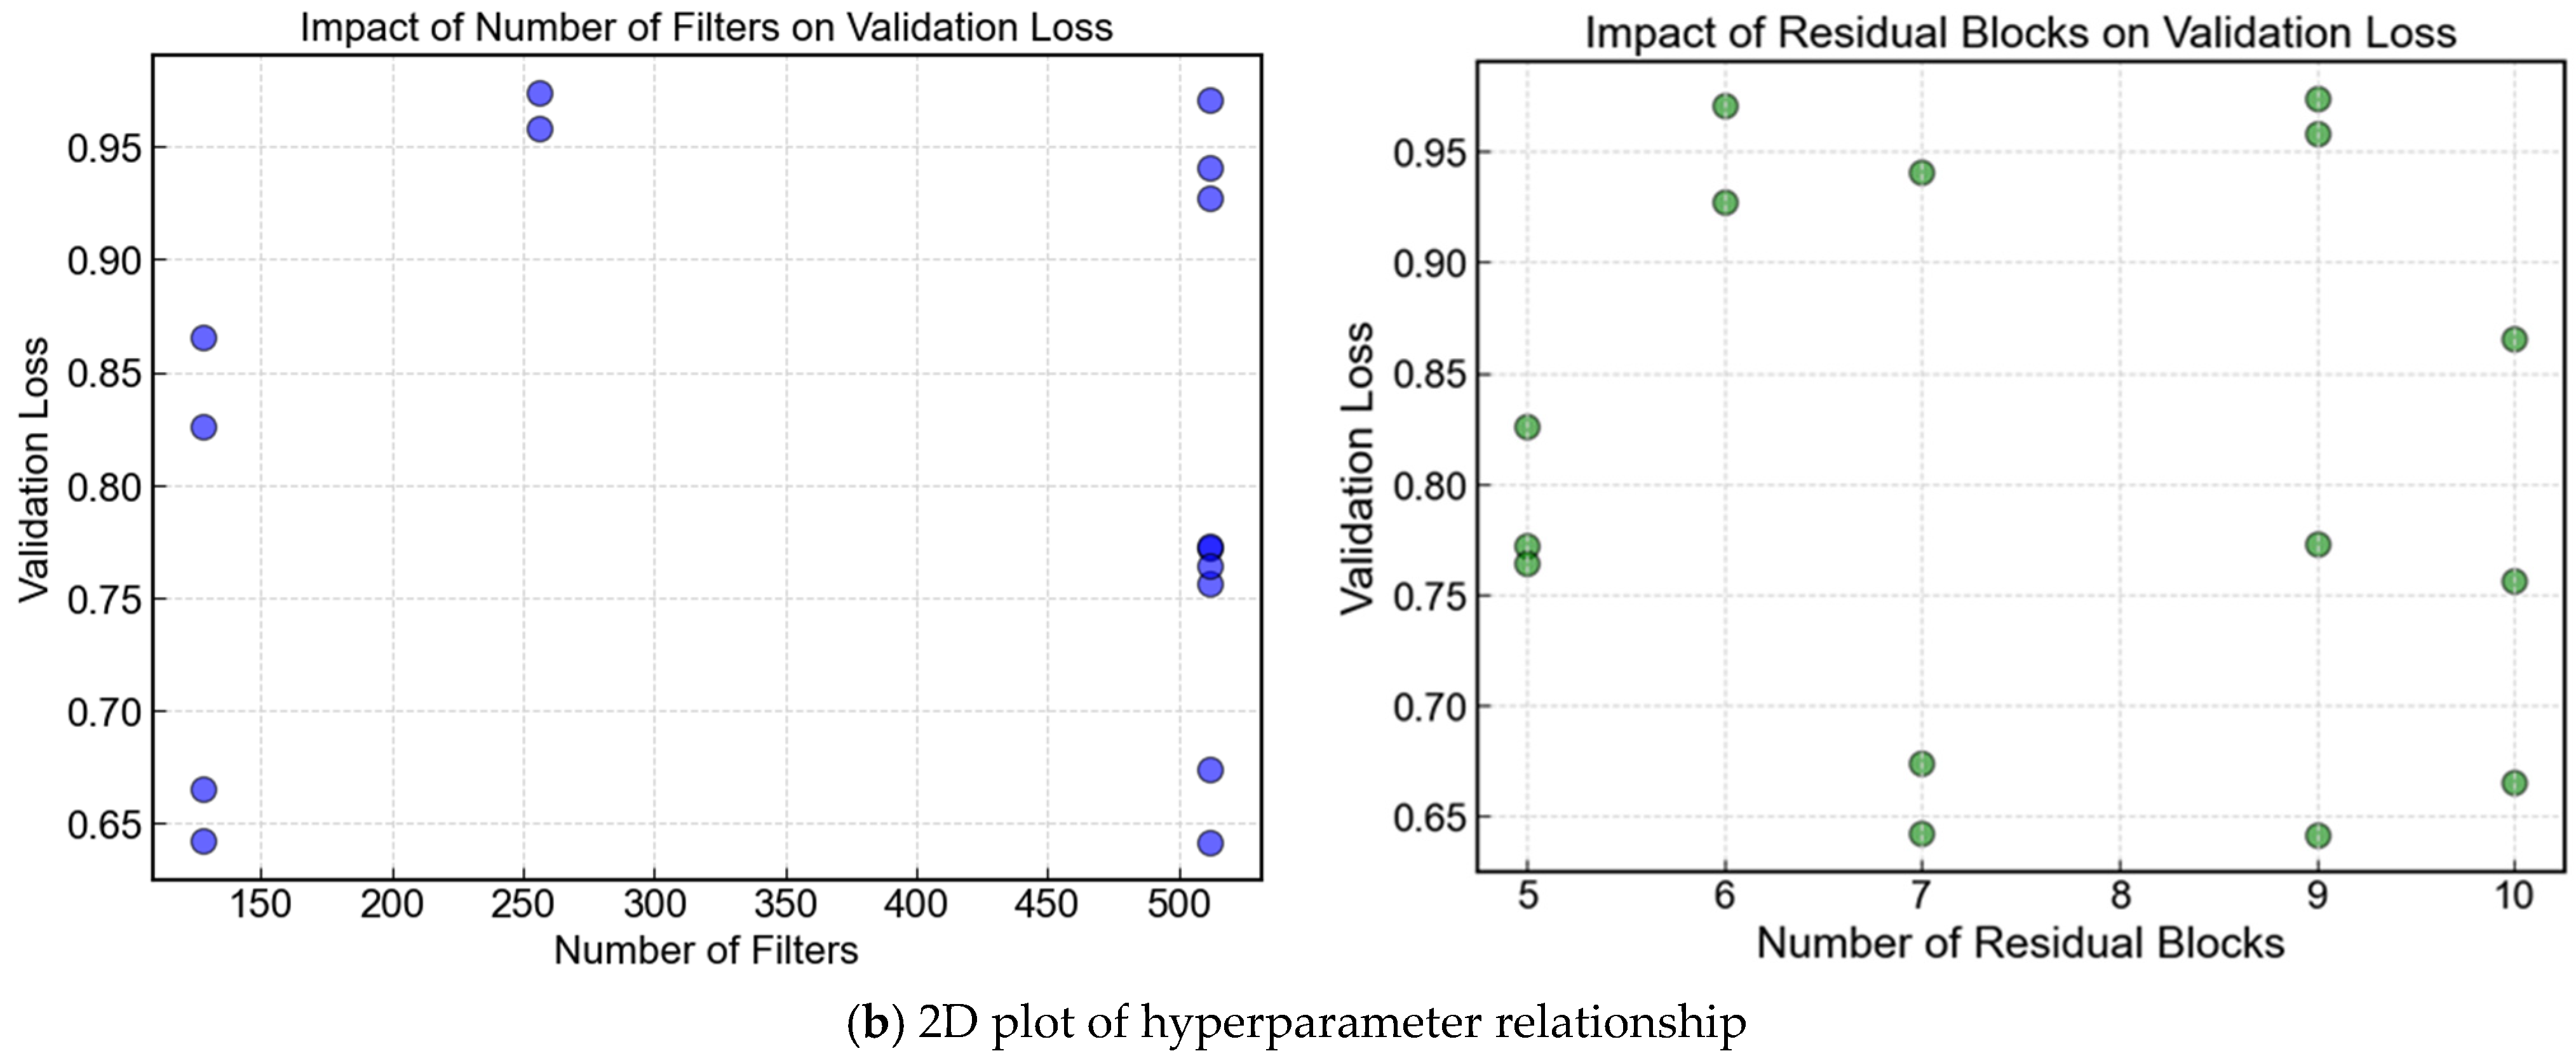
The hyperparameter optimization process was carried out using random search with Keras Tuner, with the aim of determining the optimal values of key hyperparameters in the deep learning model. In this study, the search space was defined as follows: the number of filters in the convolutional layers ∈ {128, 256, 512}, the number of residual blocks ∈ {4, 6, 8}, the number of attention heads in the multi-head attention mechanism ∈ {8, 16, 32}, and the initial learning rate of the Adam optimizer ∈ {1 × 10⁻³, 5 × 10⁻⁴, 1 × 10⁻⁴}. The hyperparameter search was conducted on the development set described in Section 3.3, using 5-fold cross-validation grouped by experimental program as the validation strategy: for each candidate hyperparameter configuration, the development set was divided into five non-overlapping folds, each in turn serving as the validation set while the remaining four folds served as the training set. The validation losses over the five folds were computed and their average was taken as the overall performance metric of that configuration. In total, 50 candidate configurations were evaluated by random search, which was terminated when the average validation loss ceased to decrease markedly and the predefined maximum number of trials was reached. The configuration with the smallest average validation loss was finally selected as the optimal hyperparameter combination. The results of hyperparameter tuning are as follows:
- (1)
- Number of filters: It was found that the optimal number of filters in the convolutional layers is 256. This value provides a balance between capturing sufficient features and avoiding an overly complex model.
- (2)
- Number of residual blocks: The best-performing model contains 6 residual blocks, enabling the network to effectively extract both low-level and high-level features while maintaining a manageable number of parameters.
- (3)
- Number of attention heads: The optimal number of attention heads was determined to be 8. This configuration allows the model to focus on important parts of the input and capture long-range dependencies without overfitting.
- (4)
- Learning rate: The optimal learning rate for training the model was determined to be 0.0001. This relatively low learning rate ensures smooth convergence and reduces the risk of overshooting the optimum during training.
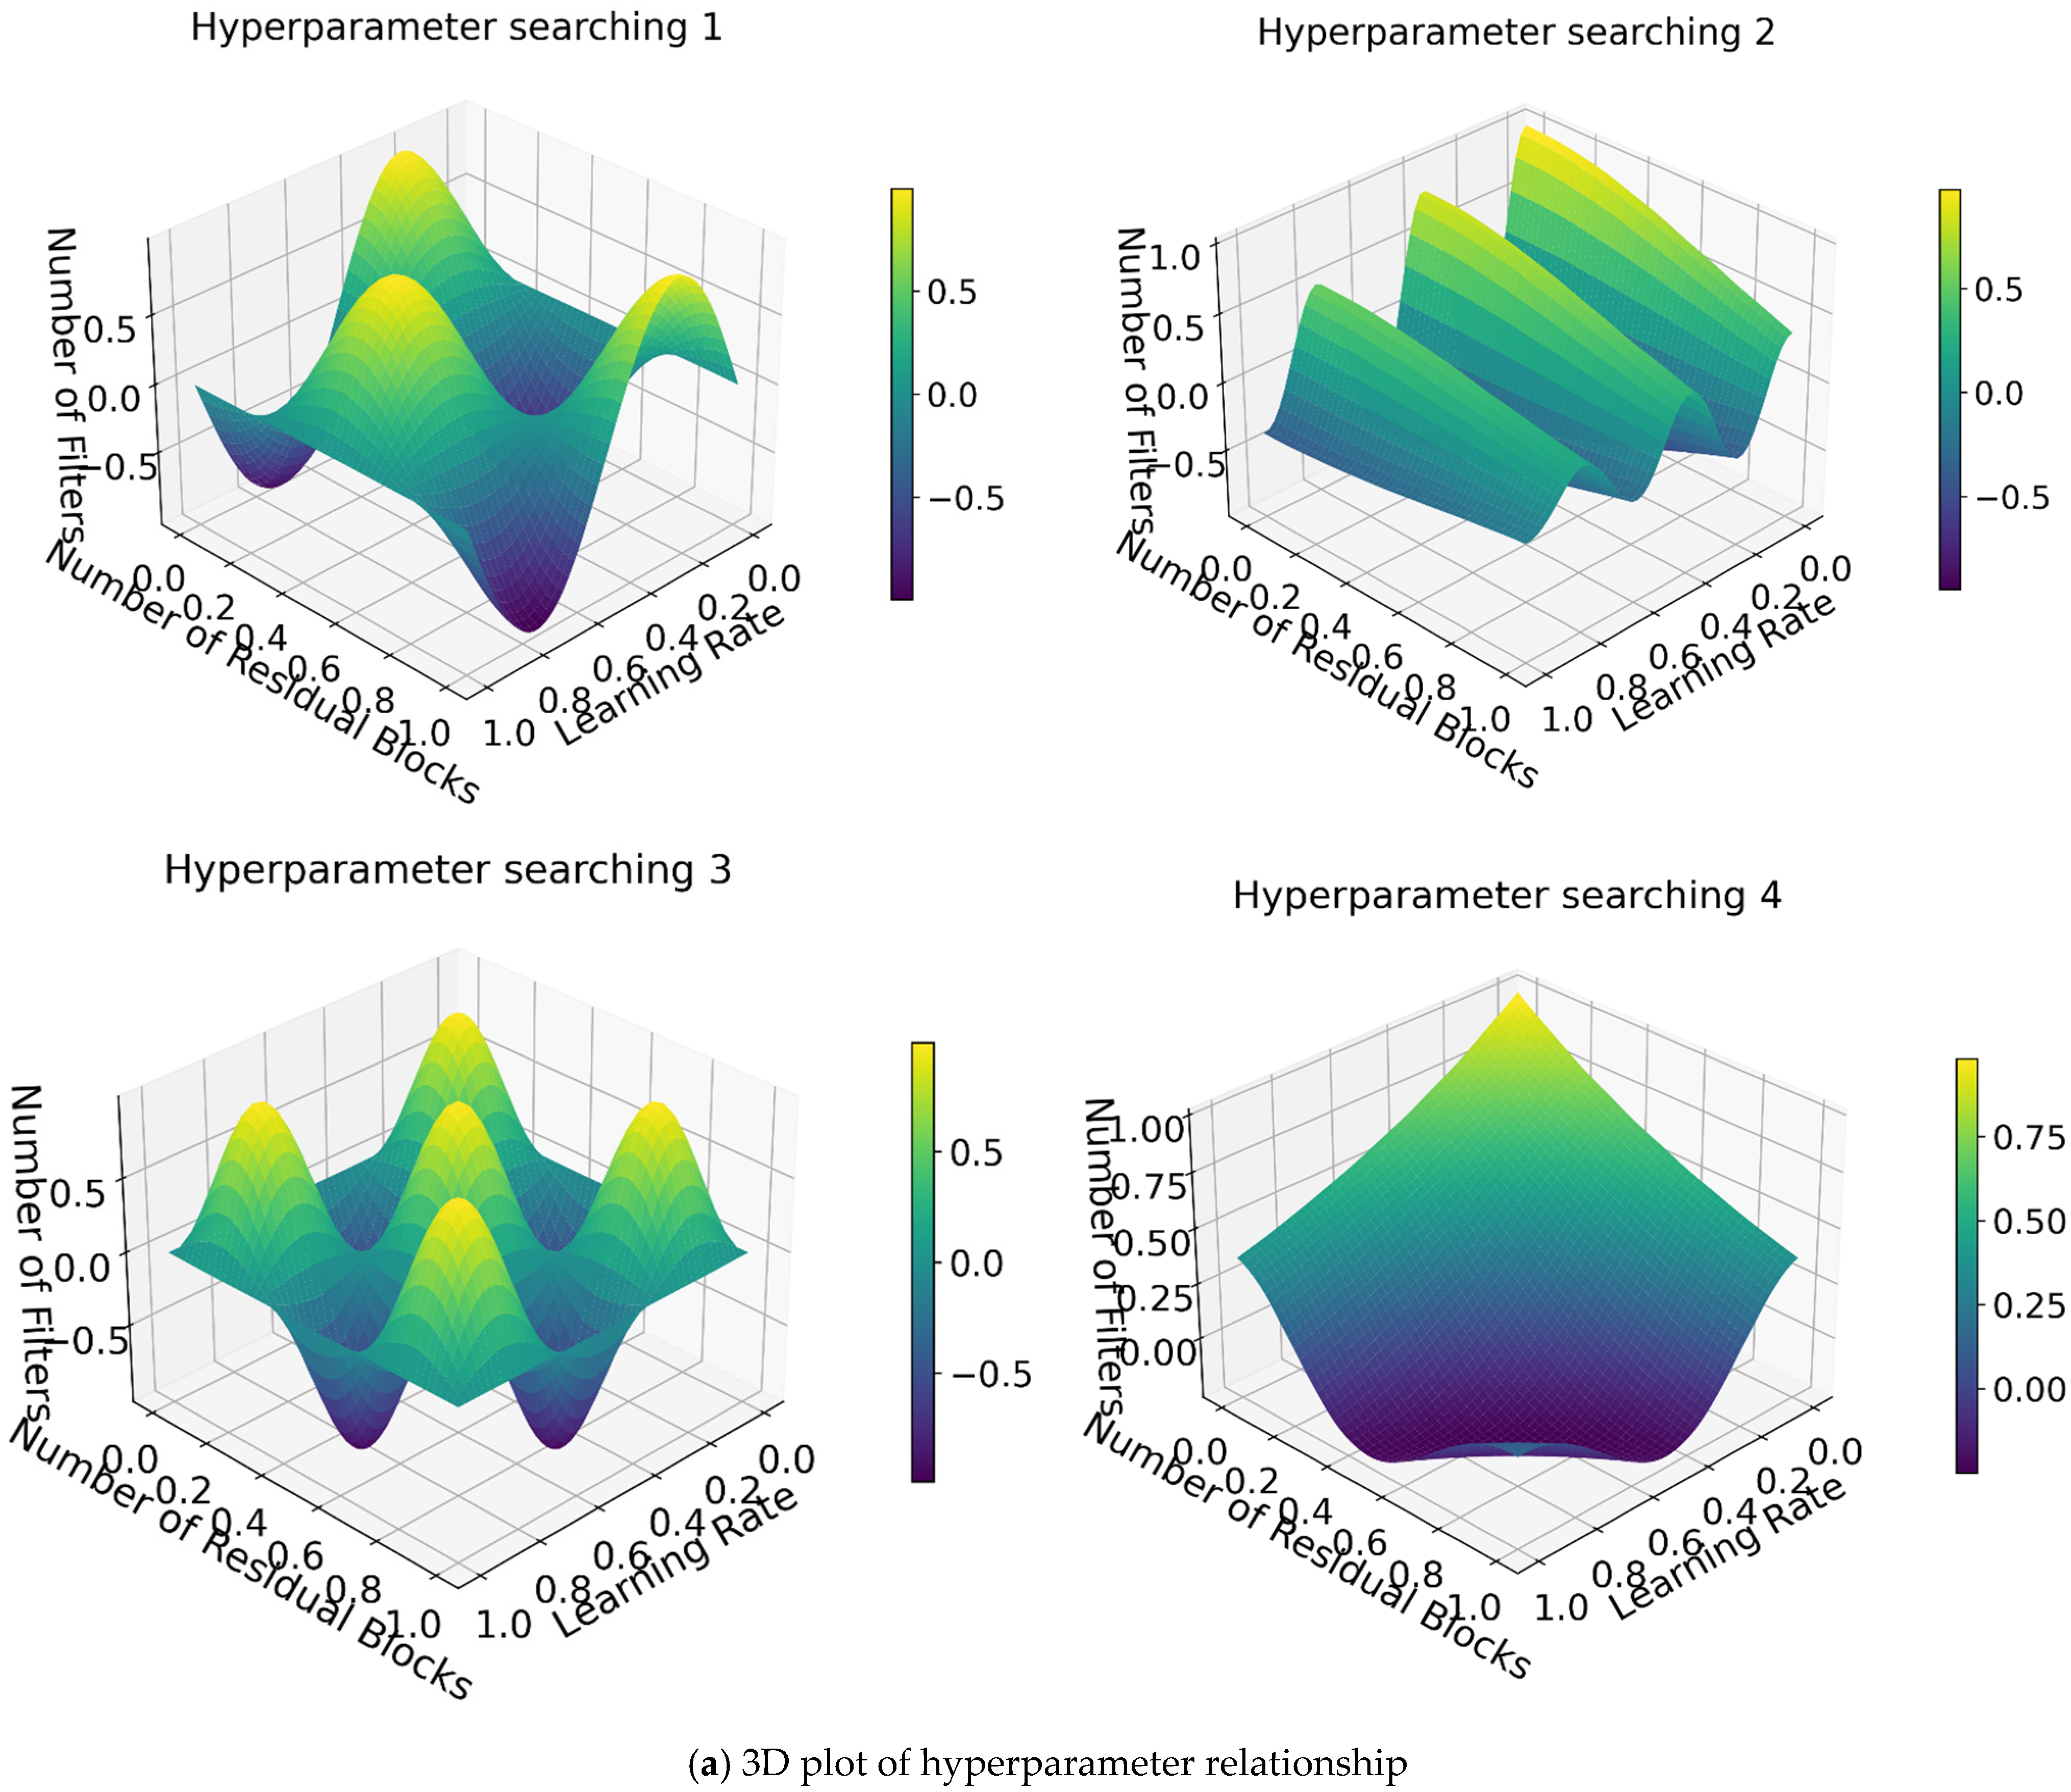
This combination of hyperparameters enables the deep learning model to achieve higher performance in reconstructing masked data and predicting shear capacity, as shown in Figure 5. The optimized architecture strikes a balance between complexity and generalization, which is crucial for attaining high predictive accuracy while maintaining robust performance on unseen data.
Figure 5.
Effect of hyperparameter optimization.
4.3. Image Reconstruction
The image reconstruction process is carried out using an autoencoder-based deep learning model to recover the masked portions of the input data. The autoencoder is trained to minimize the mean squared error (MSE) between the original images and the reconstructed images. Figure 6 illustrates examples of the original, masked, and reconstructed images. The original images represent the complete feature set of the RC beams, while the masked images simulate real-world incomplete data scenarios by obscuring 50% of the features. The reconstructed images demonstrate the model’s ability to accurately infer the missing features and restore the spatial relationships among beam properties. The 3 × 4 feature layout shown in Figure 6 corresponds to the pre-upsampling stage; when fed into the network, these feature maps are uniformly rescaled to 8 × 8 × 3 images as described in Section 2.2.
Figure 6.
Examples of original, mask, and reconstructed images.
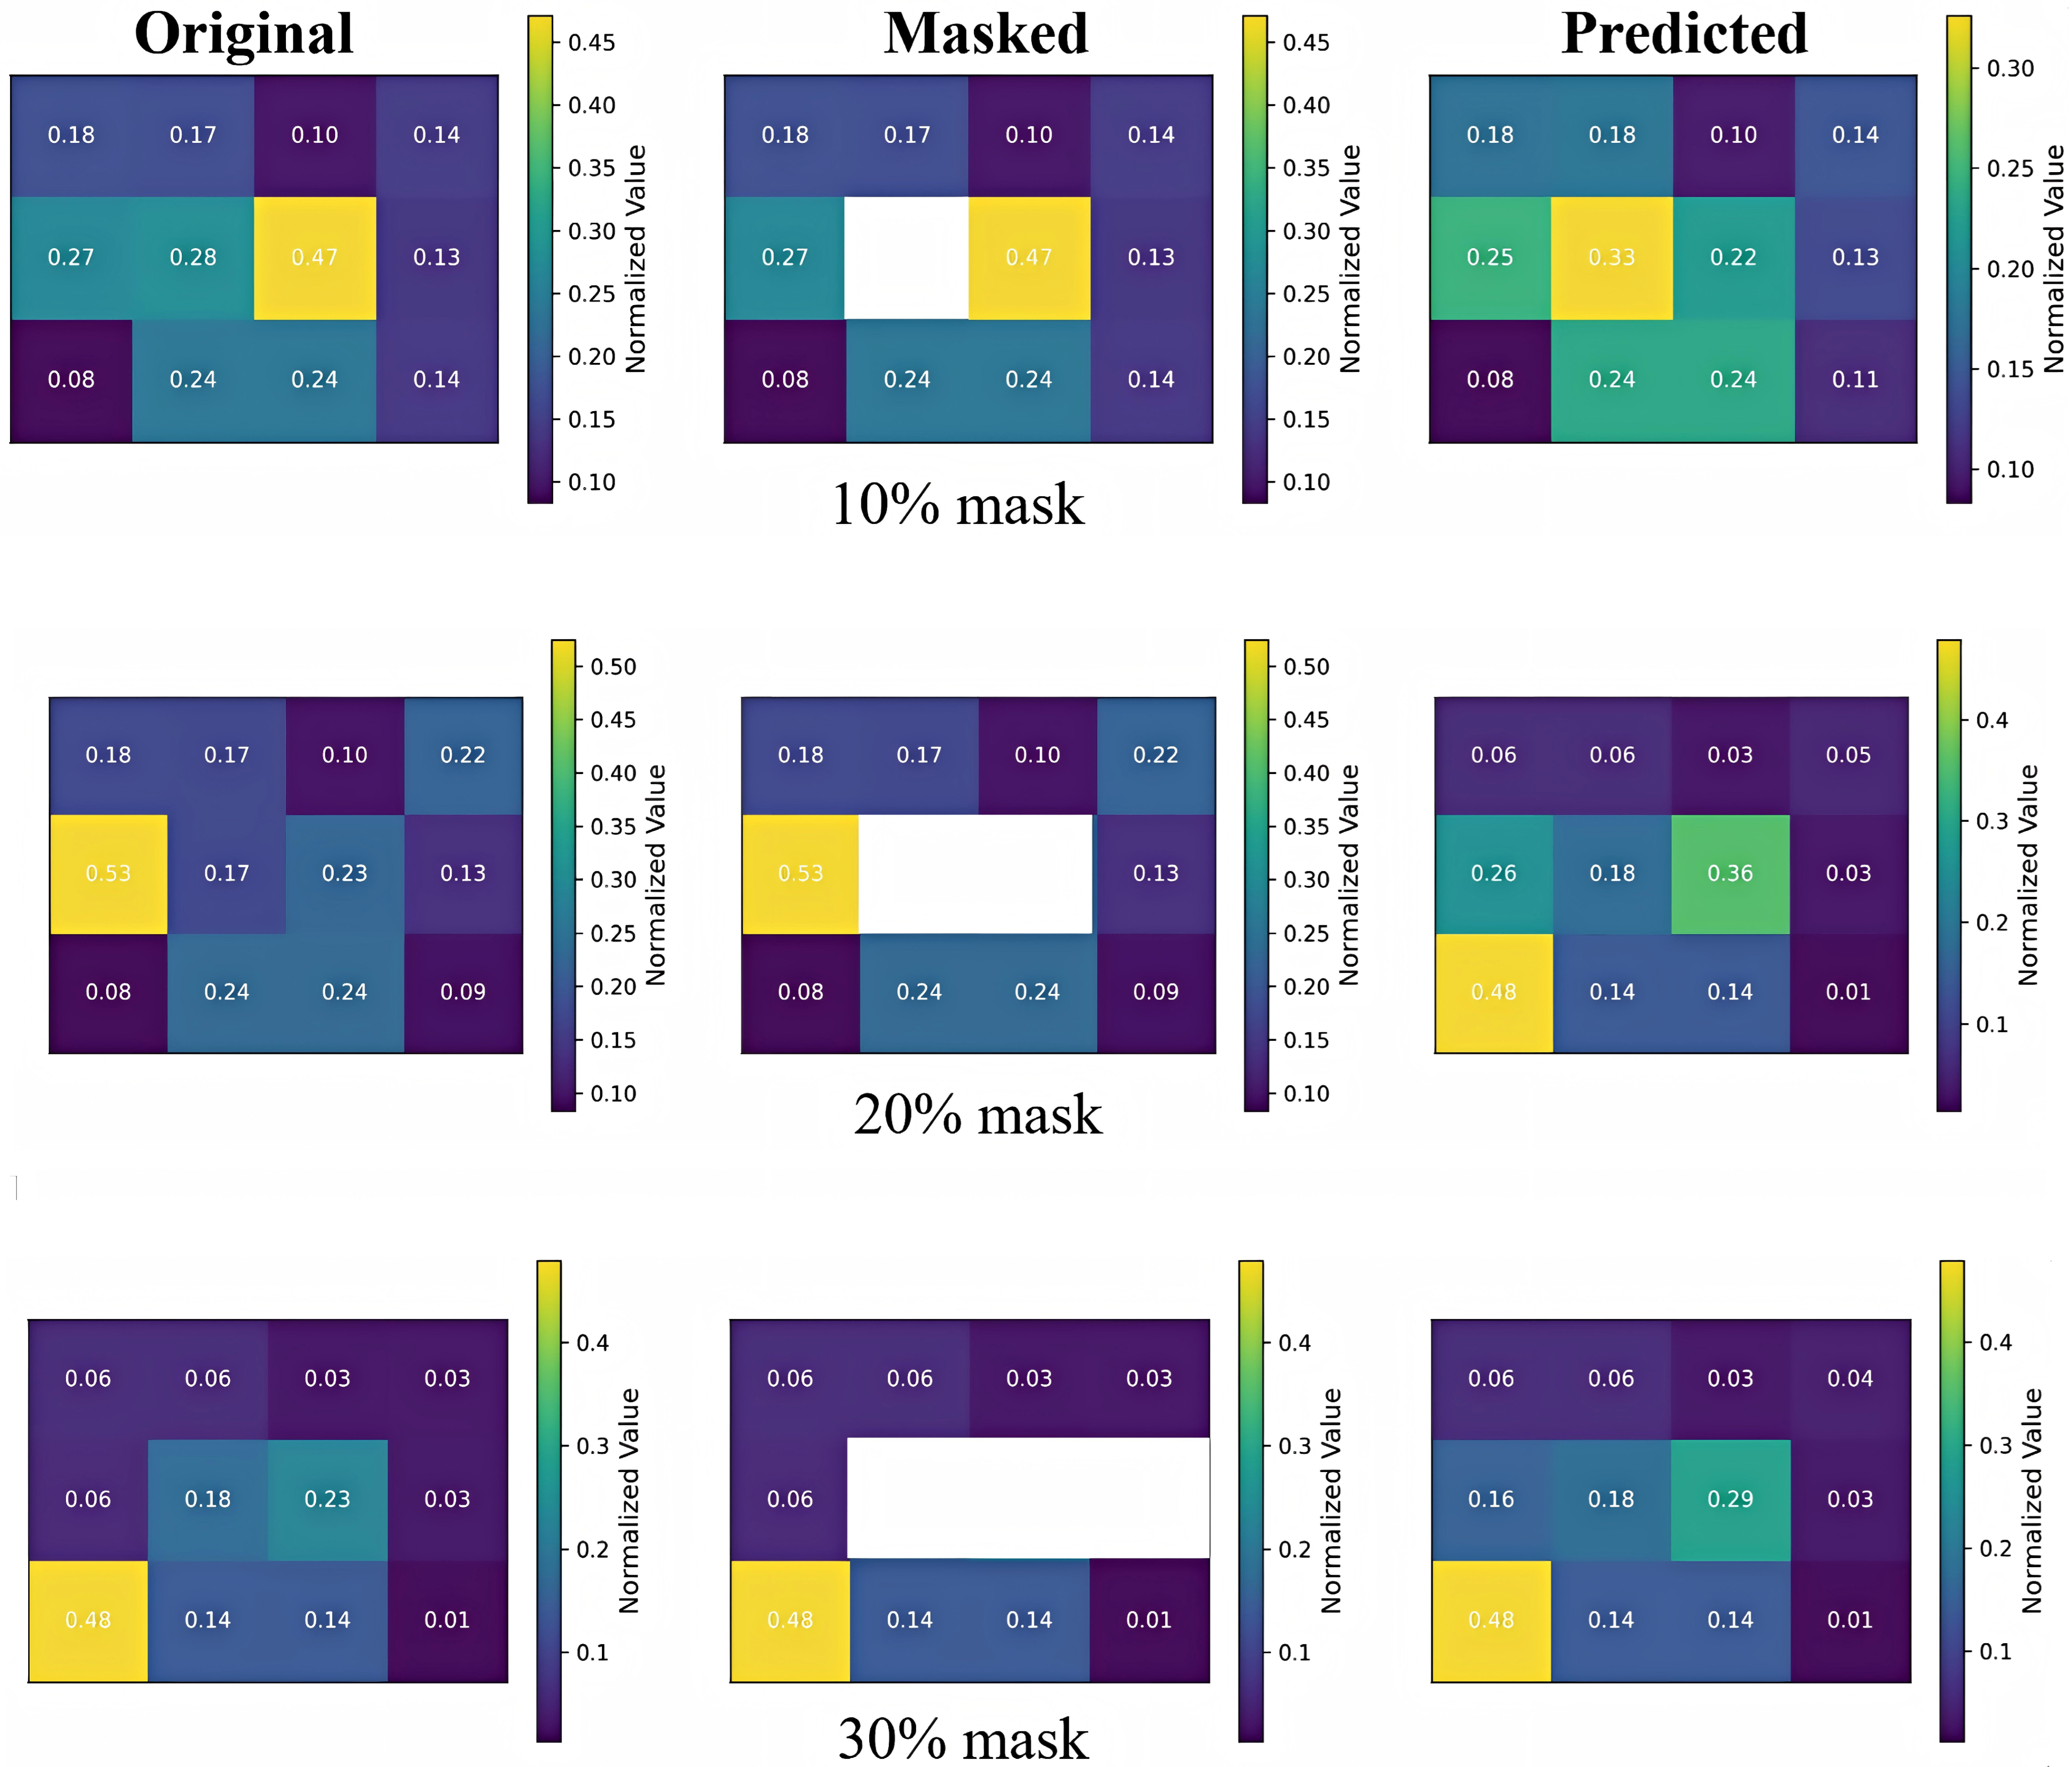
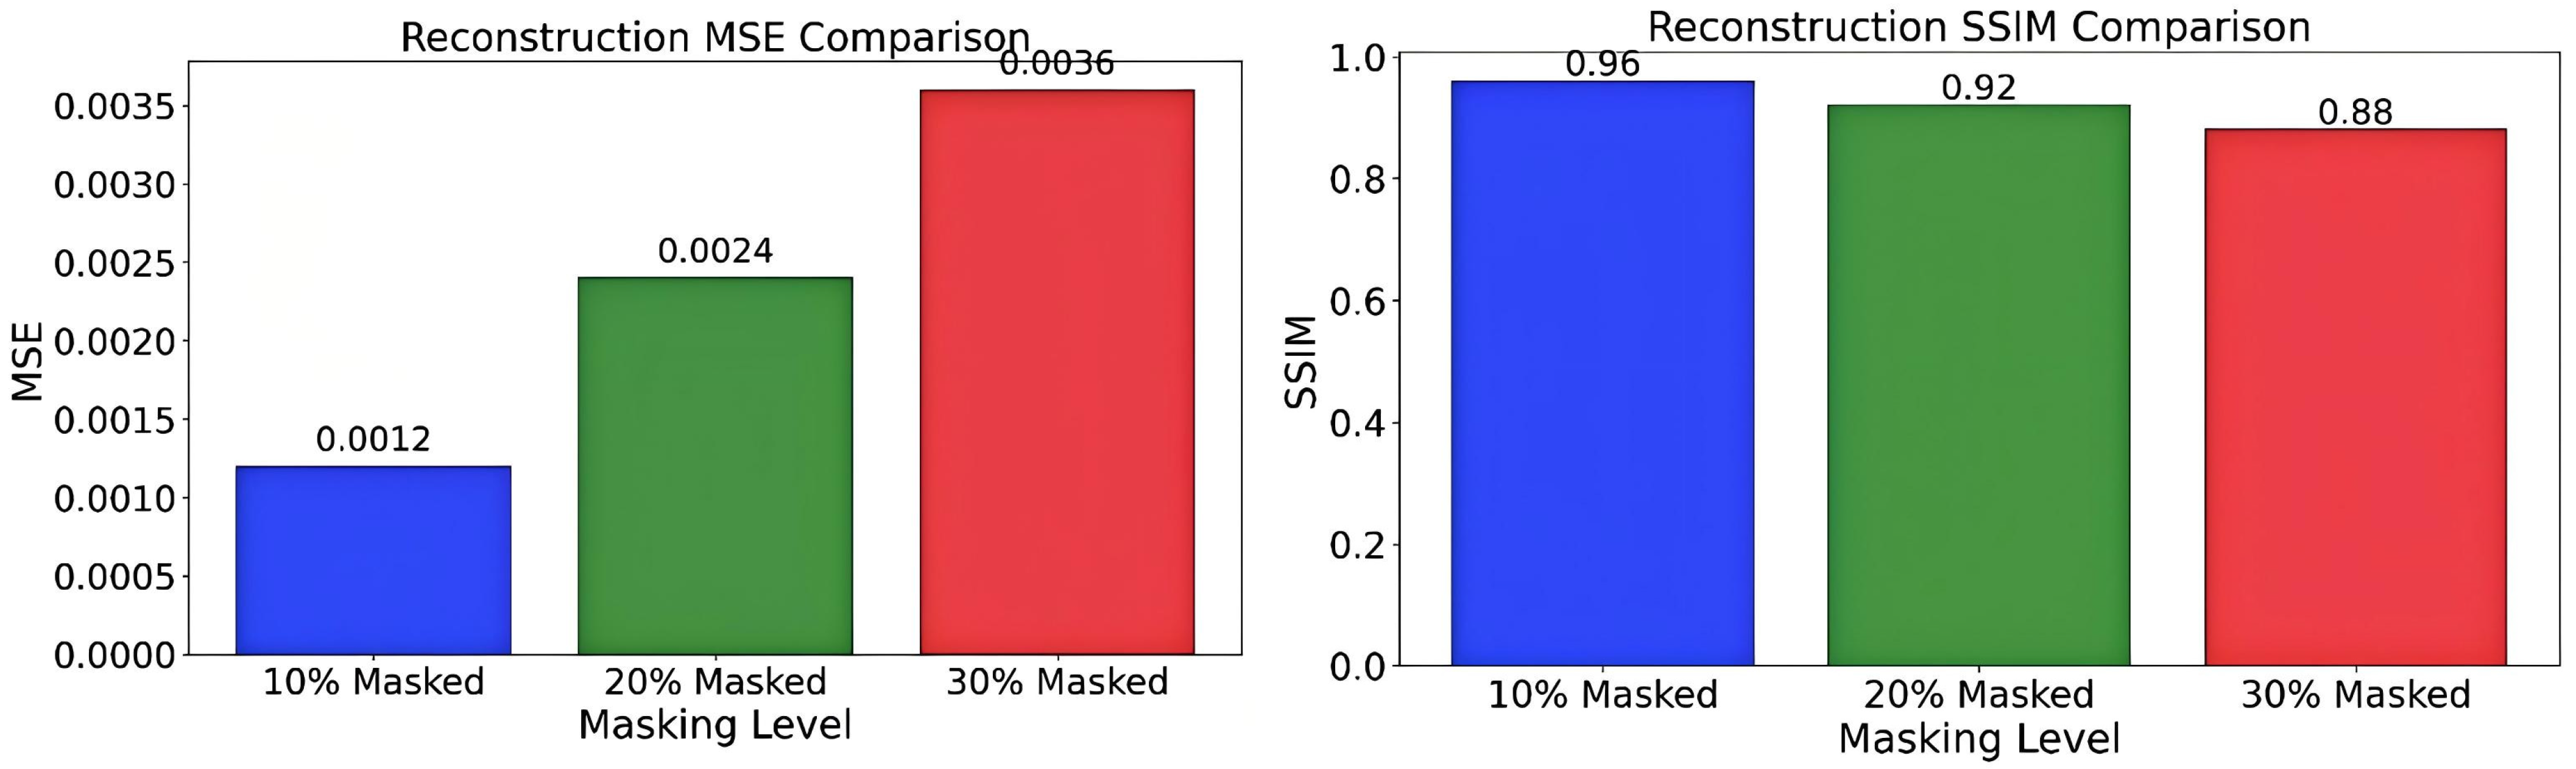
Further analysis indicates that across different levels of data masking (10%, 20%, and 30%), the reconstruction accuracy remains robust. The autoencoder consistently captures local and global patterns, ensuring reliable reconstruction performance even in the presence of extensive missing data. Under 10% masking, the autoencoder achieves an MSE of 0.0012 and an SSIM of 0.96, indicating high reconstruction fidelity, as shown in Figure 7. As the masking level increases to 20%, the MSE rises slightly to 0.0024, while the SSIM remains at a strong level of 0.92. For 30% masking, the MSE reaches 0.0036 and the SSIM decreases to 0.88, suggesting that the model is capable of handling substantial data loss while maintaining acceptable reconstruction quality. These results highlight the effectiveness of the autoencoder in recovering missing features, enabling the subsequent predictive model to leverage a comprehensive and accurate dataset and thereby improving the reliability of shear capacity prediction.
Figure 7.
The original, masked and predicted results.
4.4. Prediction Accuracy
The prediction accuracy of the proposed deep learning framework was evaluated using the reconstructed dataset. To assess the model’s performance comprehensively, several evaluation metrics were employed, including Mean Absolute Error (MAE), Mean Absolute Percentage Error (MAPE), Root Mean Squared Error (RMSE), Coefficient of Determination (R2), and Nash–Sutcliffe Efficiency Index (NSEI). Below are the definitions and formulas for each metric:
MAPE measures the average percentage error between the predicted and actual values:
RMSE evaluates the square root of the average squared difference between predicted and actual values:
in which yi refers to the actual shear capacity, refers to the predicted shear capacity, and n represents the total number of data points.
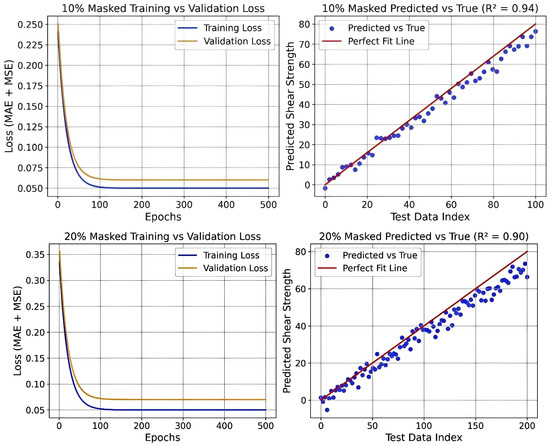
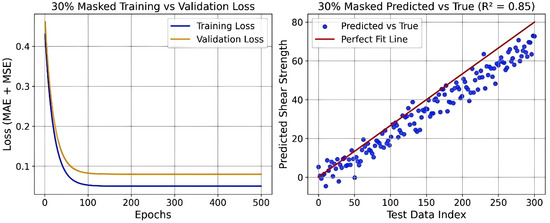
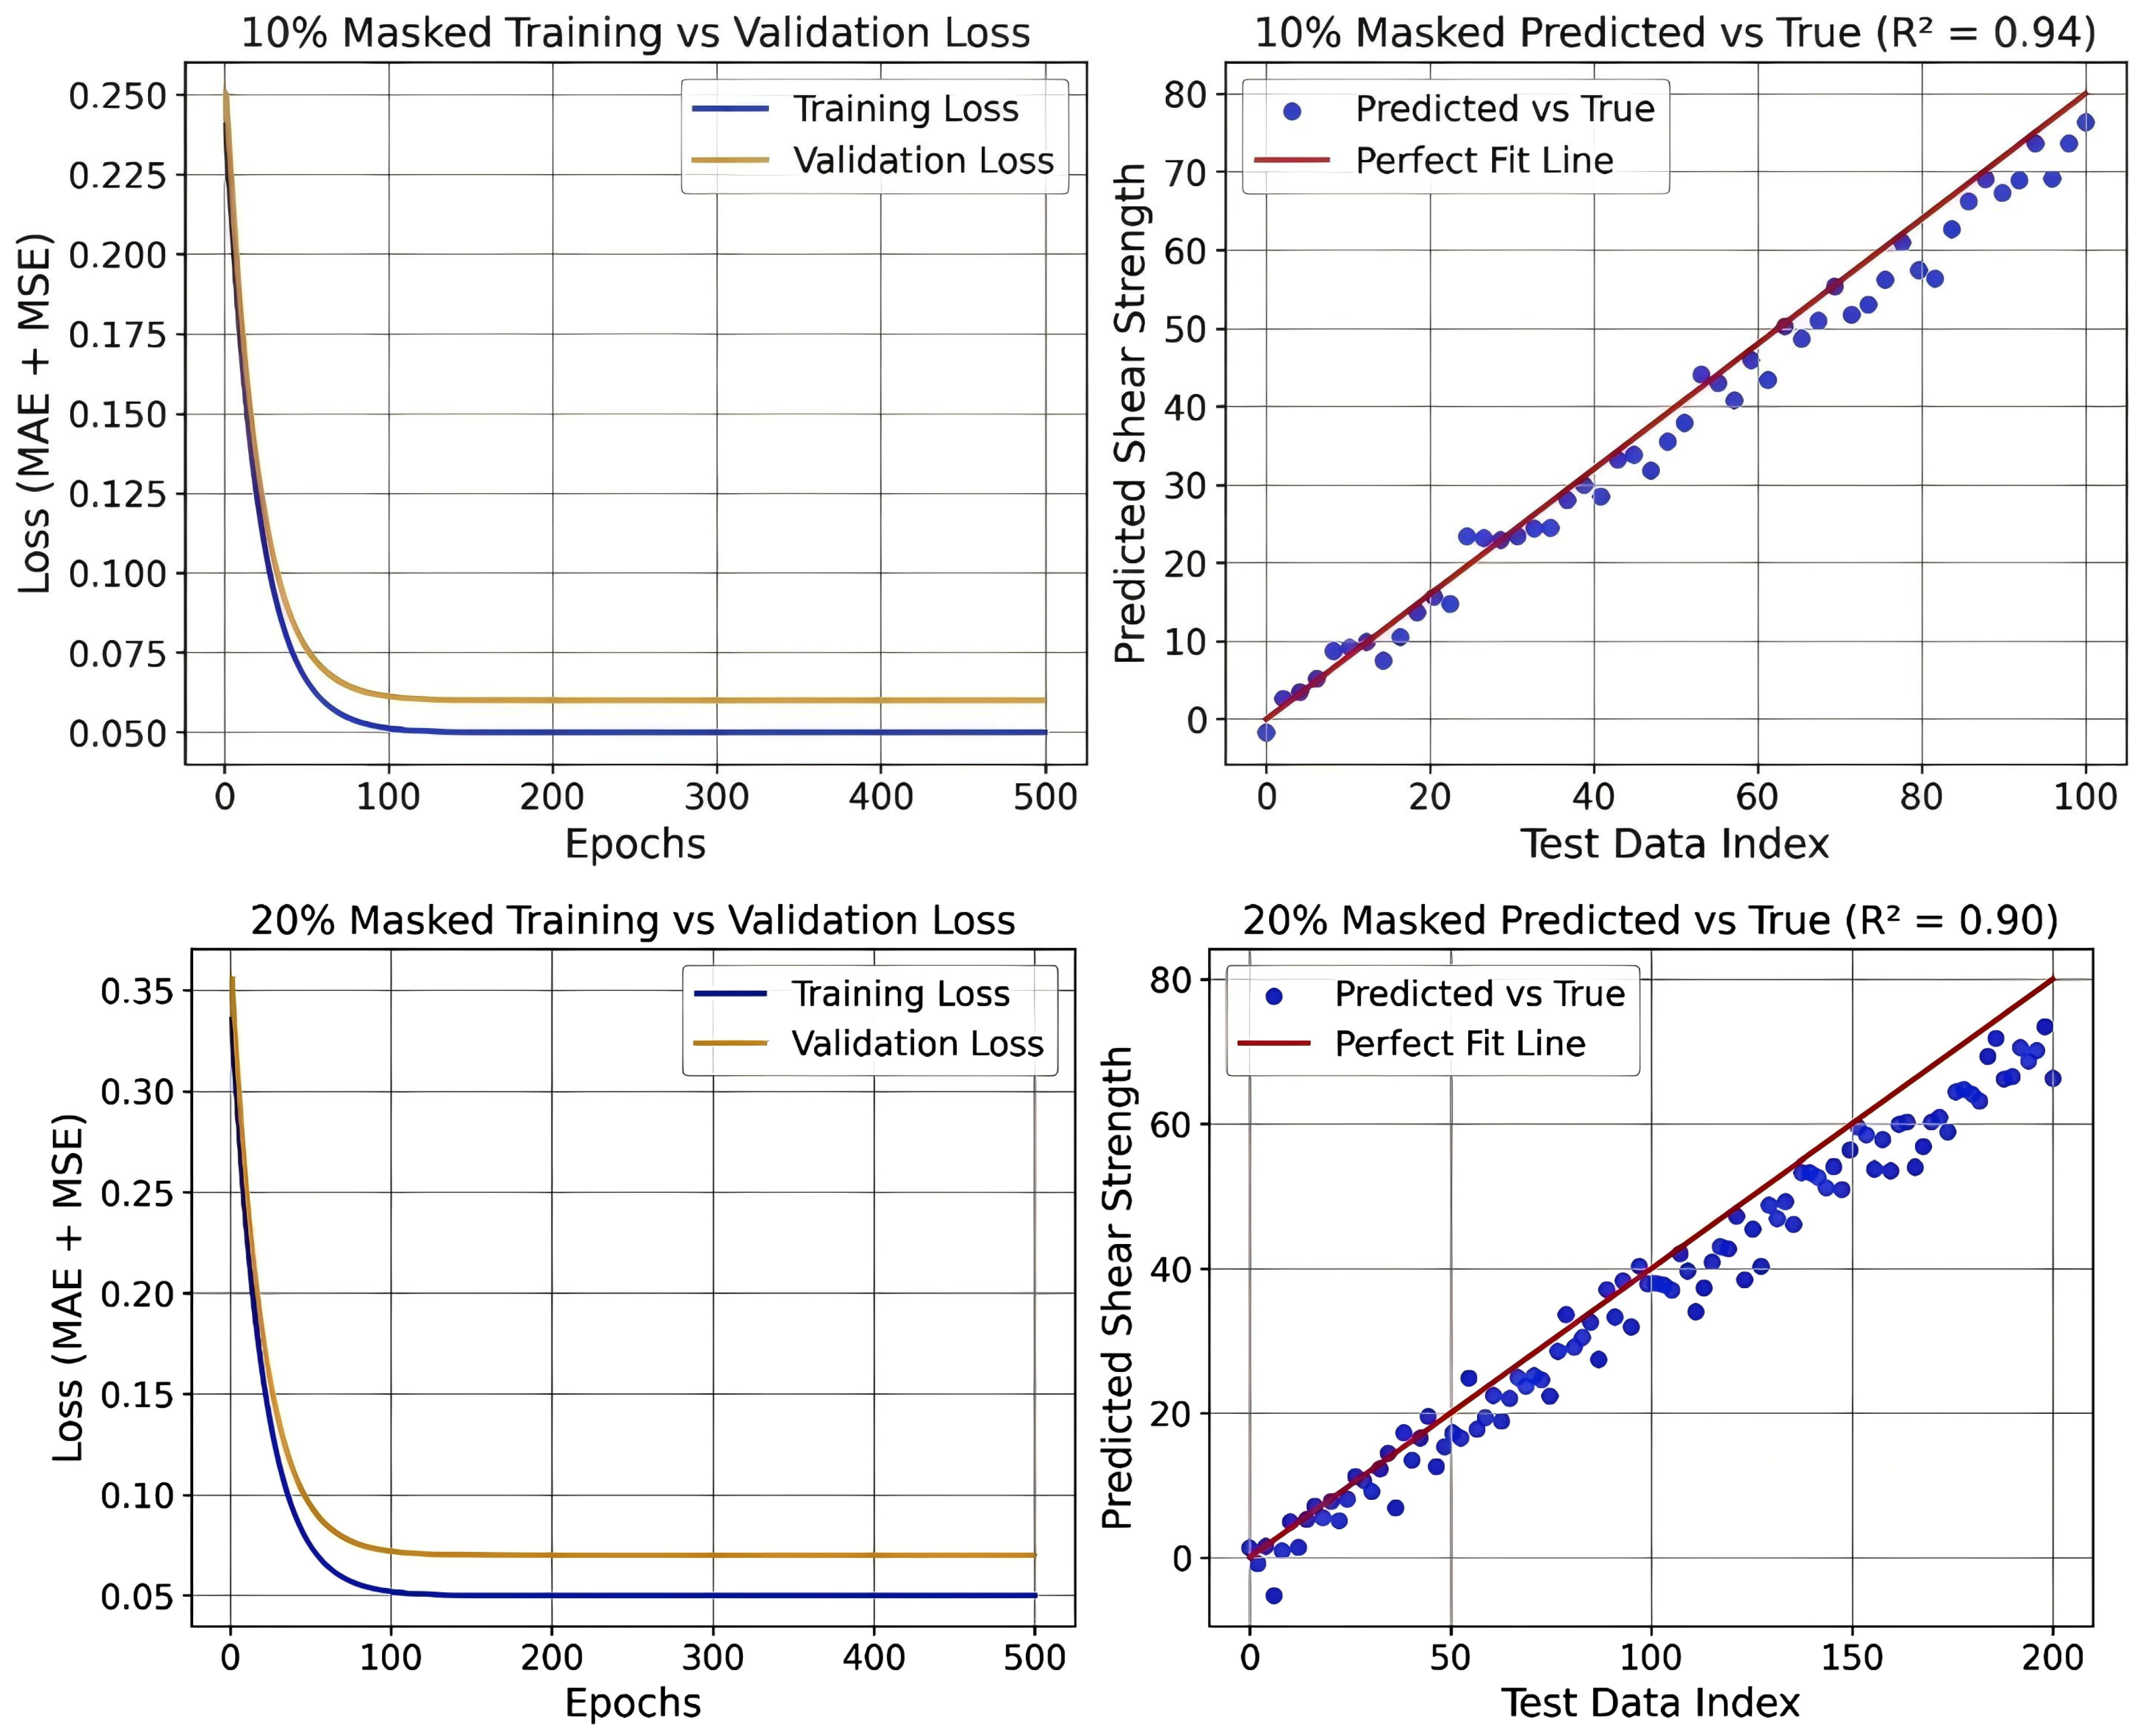
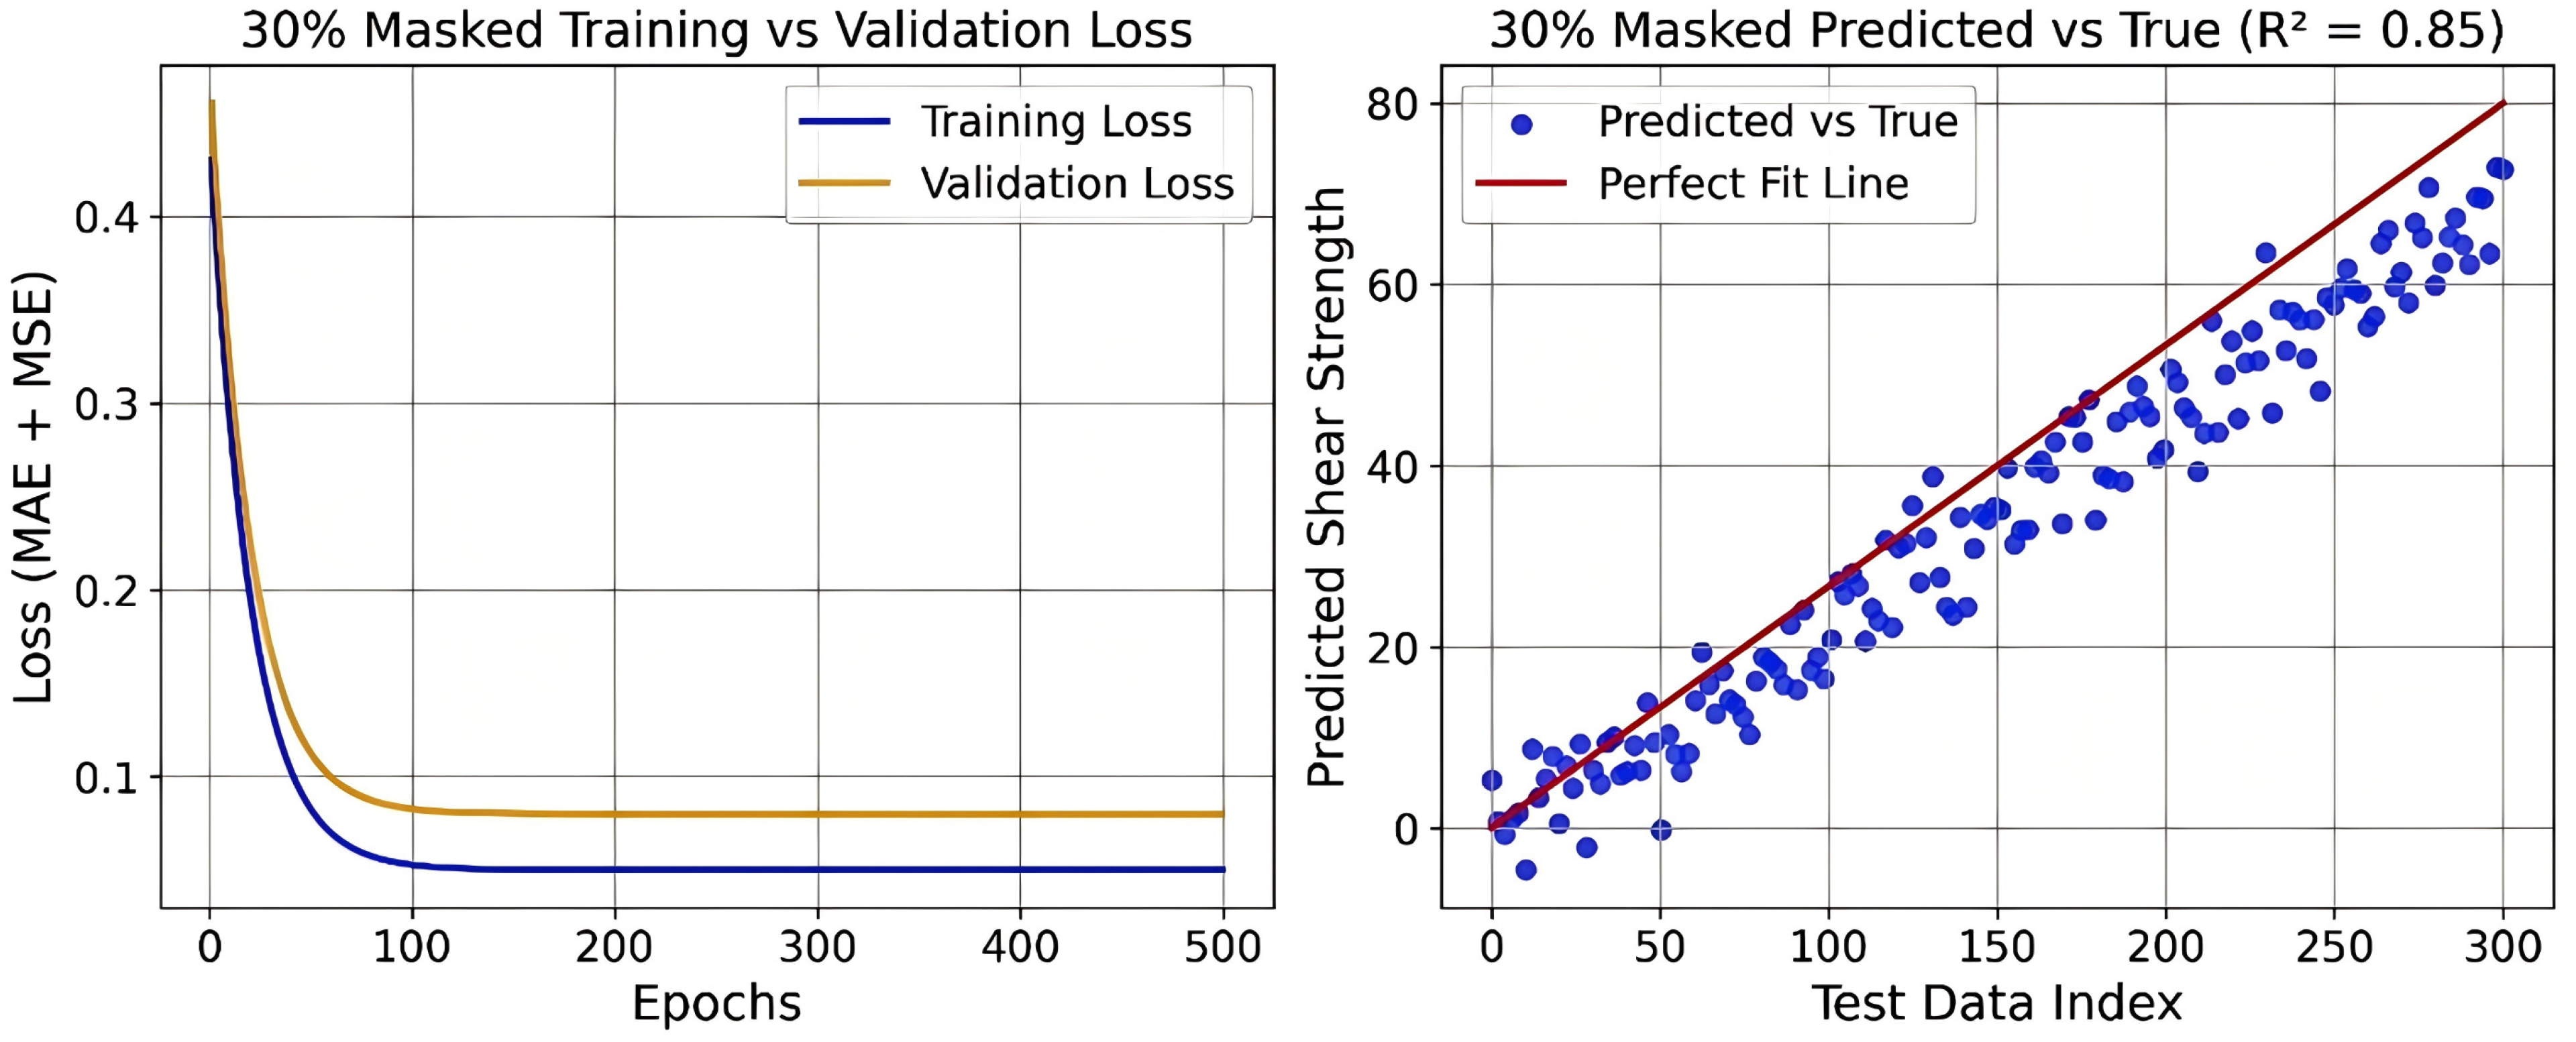
Figure 8 shows the evolution of the training loss and validation loss over 500 epochs, as well as the comparison between the predicted shear capacity and the experimentally measured values on the independent test set, in order to characterize the learning behavior and generalization ability of the model. The training loss curve (blue) drops rapidly at the initial stage and then stabilizes at around 0.05, indicating that the model is able to effectively extract useful features from the training data. The validation loss curve (orange) follows a trend highly consistent with that of the training loss and exhibits no obvious divergence, suggesting that the degree of overfitting is low and that the model has good generalization performance.
Figure 8.
Training and validation loss with prediction accuracy.
According to the data partitioning strategy described in Section 3.3, the full dataset is first grouped by experimental program into a development set and an independent test set. The training/validation loss curves in Figure 8 are all computed based on a fixed train–validation split within the development set, whereas the scatter plot of predicted versus measured values on the right-hand side, together with the corresponding (R2 = 0.94), is obtained entirely from the independent test set. The hyperparameters are determined by group-wise 5-fold cross-validation on the development set combined with random search using Keras Tuner. The data in the independent test set do not participate at any stage in standardization parameter estimation, model selection, or early-stopping criterion setting, but are used solely for the final performance evaluation. This effectively prevents information leakage from the test set and ensures the objectivity and reproducibility of the performance assessment.
From the distribution of the predicted–measured scatter points, it can be seen that the data are tightly clustered around the ideal diagonal line, reflecting good agreement between the model predictions and the experimental shear capacities, while (R2 = 0.94) further quantifies the high degree of correlation between them. In summary, the results shown in Figure 8 indicate that the proposed deep learning framework exhibits high accuracy and reliability in both missing-information reconstruction and shear capacity prediction for slender beams without shear reinforcement.
4.5. Comparison with Baseline Models
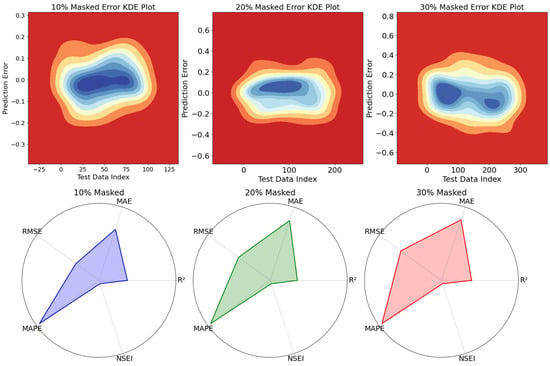
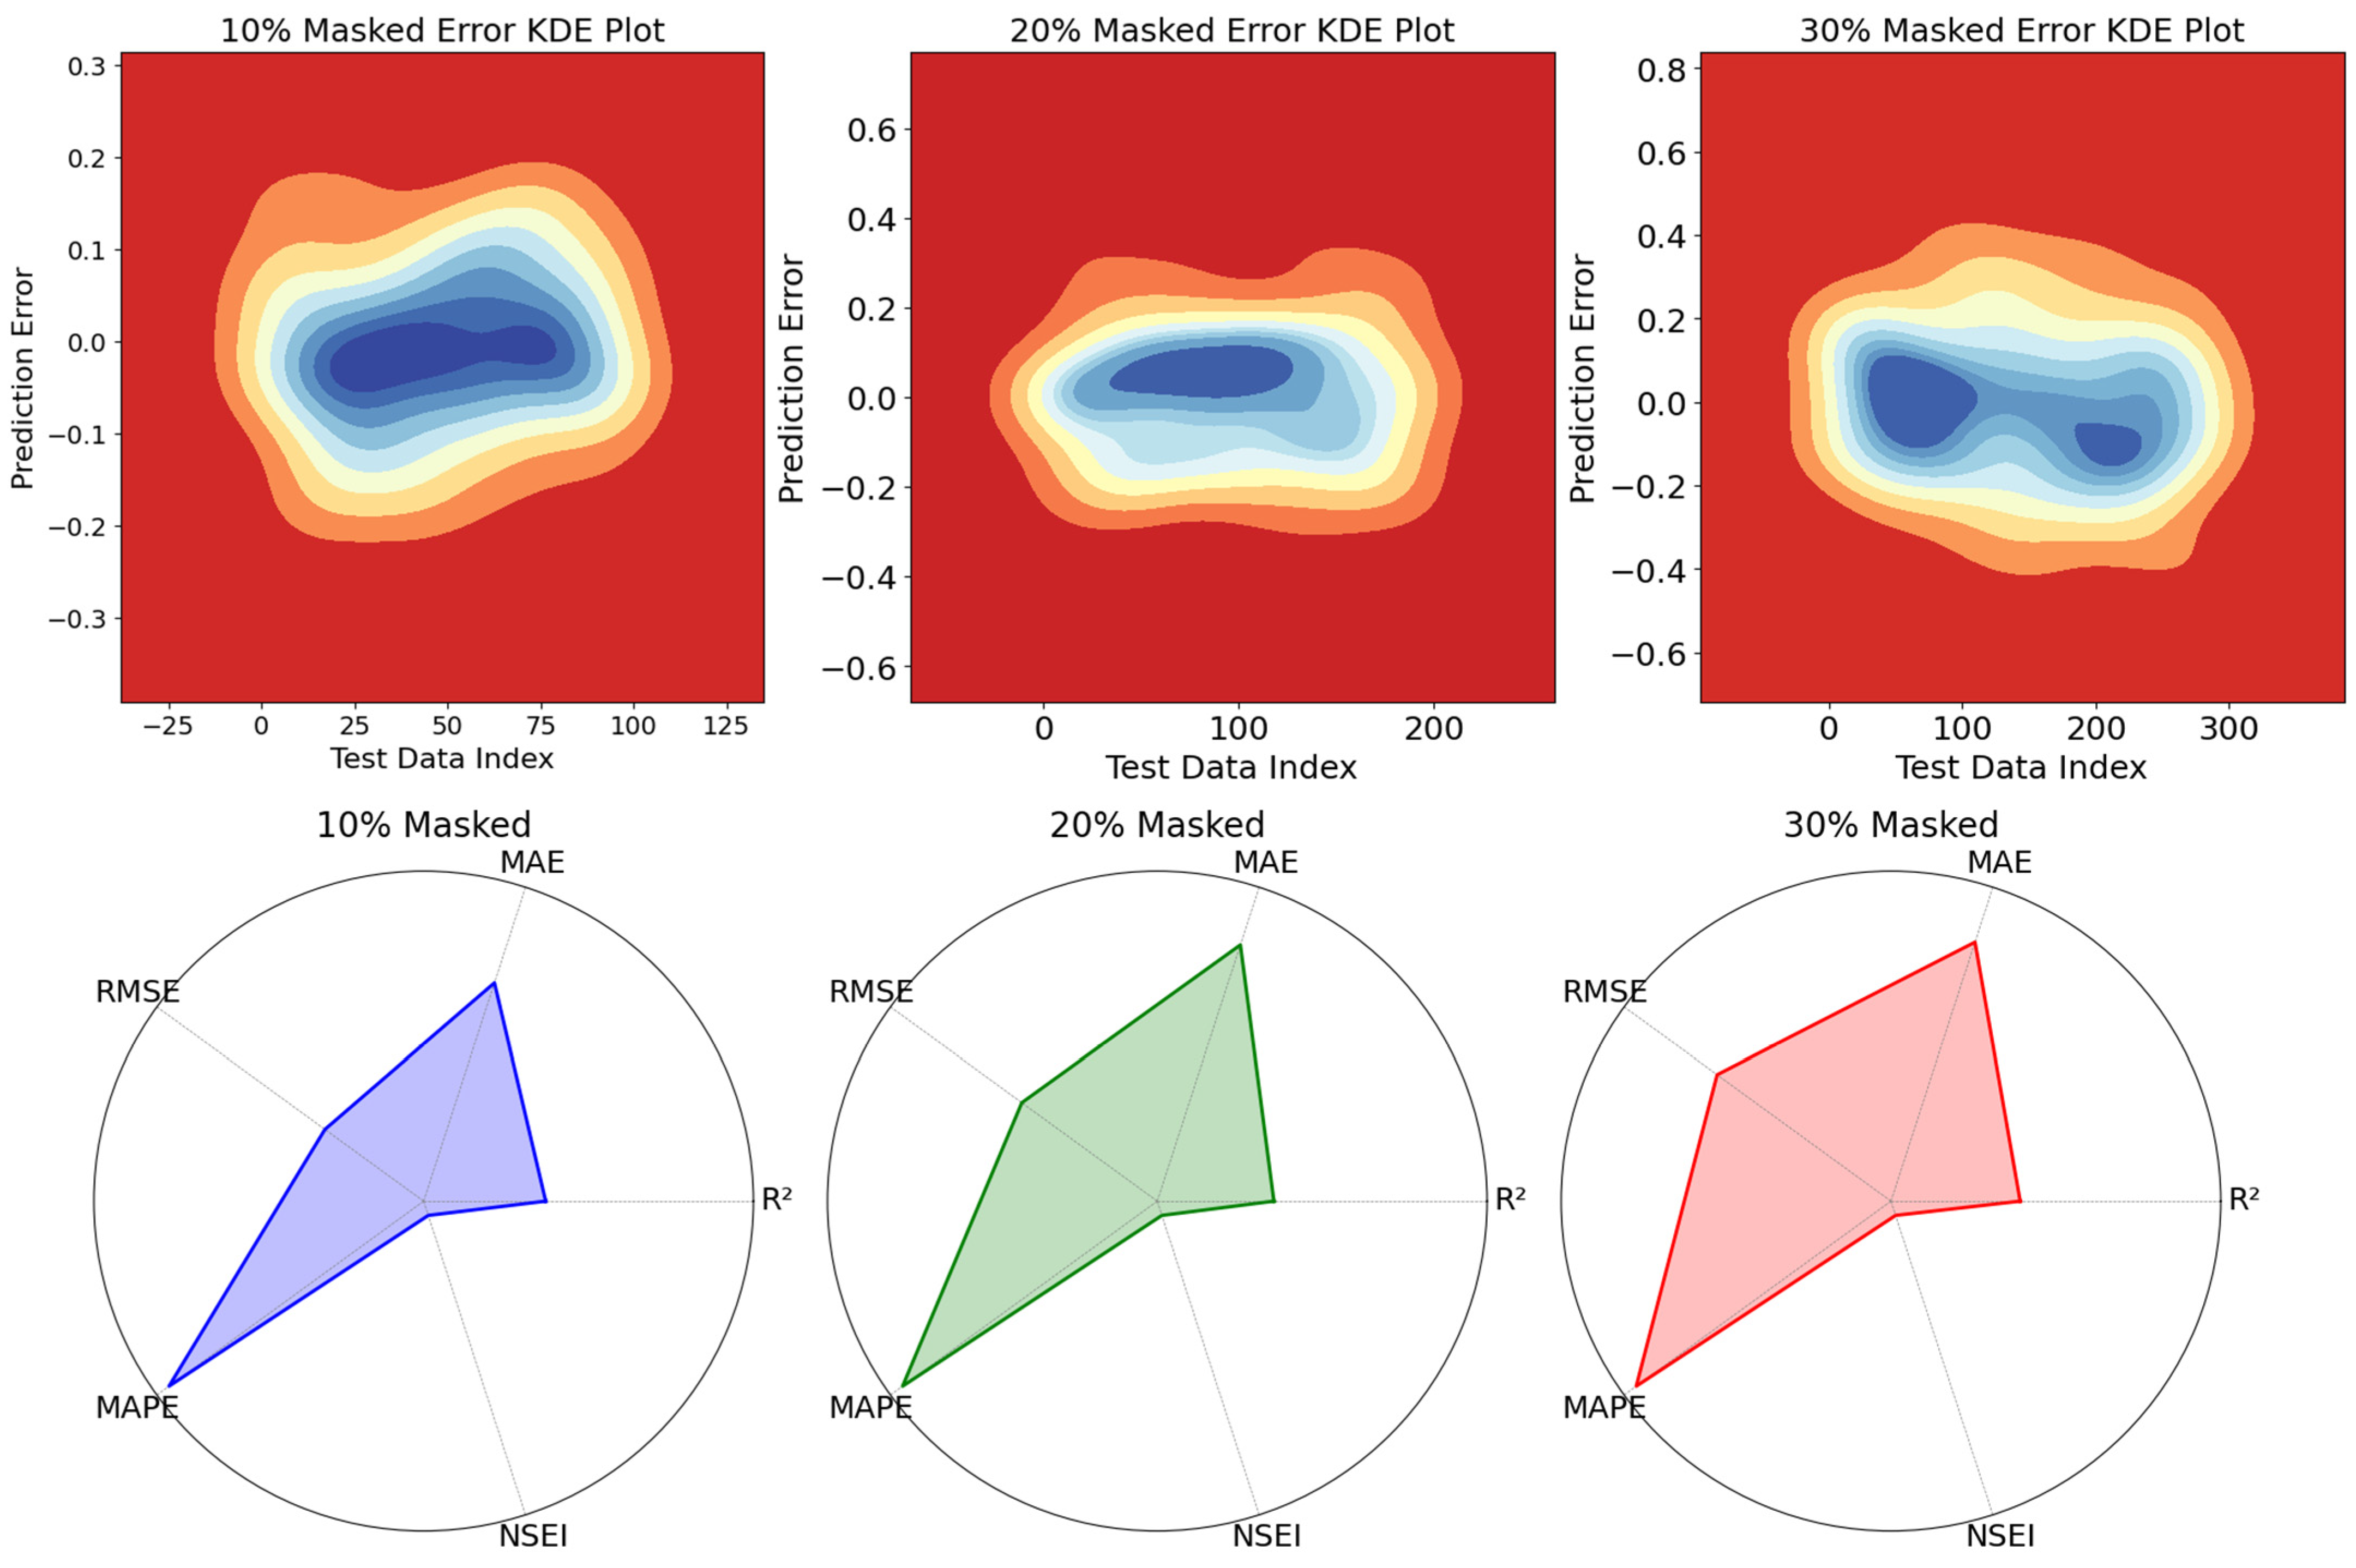
The proposed deep learning framework demonstrates superior performance compared to the baseline methods (ACI 318 and Eurocode 2) under different levels of data masking (10%, 20%, and 30%), as detailed in Table 1 and Figure 9. The quantitative results for various performance metrics, including R2, MAE, RMSE, MAPE, and NSEI, are summarized below.
Table 1.
Comparison of analytical and existing models.
Figure 9.
Results of different models.
Under 20% masking, the proposed method maintains strong performance, with an (R2) of 0.90, compared with 0.75 for ACI 318 and 0.73 for Eurocode 2. The MAE of the proposed method increases slightly to 0.07, but remains significantly lower than that of ACI 318 (0.15) and Eurocode 2 (0.17). The RMSE of the proposed method is 0.09, whereas ACI 318 and Eurocode 2 yield values of 0.18 and 0.20, respectively. MAPE follows a similar trend, with the proposed method achieving 6.1%, compared with 12.3% for ACI 318 and 13.9% for Eurocode 2. The NSEI of the proposed method is 0.88, outperforming ACI 318 (0.70) and Eurocode 2 (0.68).
When the masking level increases to 30%, the proposed method still exhibits robust performance, with an RR of 0.85, compared with 0.70 for ACI 318 and 0.68 for Eurocode 2. The MAE of the proposed method rises to 0.10 but remains lower than that of ACI 318 (0.18) and Eurocode 2 (0.20). Similarly, the RMSE of the proposed method is 0.12, while ACI 318 and Eurocode 2 show higher values of 0.22 and 0.25, respectively. The MAPE of the proposed method is 8.5%, clearly superior to 14.8% (ACI 318) and 16.7% (Eurocode 2). Finally, the NSEI of the proposed method is 0.81, better than 0.65 for ACI 318 and 0.62 for Eurocode 2.
These results highlight the effectiveness of the proposed deep learning framework, which can accurately predict the shear capacity of reinforced concrete beams even under challenging conditions with high levels of missing data. It consistently outperforms traditional baseline methods across all evaluation metrics.
4.6. K-Fold Cross-Validation and Statistical Reliability Analysis
To further evaluate the sensitivity of the proposed deep learning framework to data partitioning and its statistical reliability, a group-based 5-fold cross-validation was conducted on the development set described in Section 3.3. The development set was divided into five data folds according to experimental programs; in each fold, one was used in turn as the validation set and the remaining four as the training set, and the coefficient of determination (R2), mean absolute error (MAE), and root mean squared error (RMSE) were computed separately.
Table 2 presents the mean and standard deviation of the performance metrics from the 5-fold cross-validation under different masking levels, and compares them with the results on the independent test set. It can be seen that, for all masking levels, the 5-fold average (R2) remains above 0.84 and is highly consistent with the (R2) values of the independent test set reported in Table 1. The mean MAE and RMSE are also essentially in agreement with the test-set results, and the standard deviations among folds are small, indicating that the model is insensitive to perturbations in stress state and specific data partitions, and exhibits good robustness in generalization.
Table 2.
K-fold cross-validation results and paired t-tests with code formulas.
To examine the statistical significance of the improvement in prediction accuracy of the proposed method over the code formulas, this study employs the absolute error |ypred − yexp| of each specimen in the independent test set as the sample, and performs two paired t-tests: one for the proposed method versus ACI 318, and the other for the proposed method versus Eurocode 2. The test results are summarized in Table 2. It can be seen that, under masking levels of 10%, 20%, and 30%, the p-values of both paired t-tests are all significantly less than 0.001, and the absolute values of the corresponding t-statistics are all greater than 7. This indicates that, for all masking scenarios, the proposed deep learning framework exhibits a statistically significant advantage over ACI 318 and Eurocode 2 in terms of shear capacity prediction error.
5. Conclusions
This study proposes a novel deep learning framework for predicting the shear capacity of slender reinforced concrete beams without shear reinforcement. By transforming structural data into image representations and employing deep learning with residual blocks and attention mechanisms, the framework can reconstruct missing data and achieve highly accurate predictions. The innovative use of an autoencoder for data reconstruction, together with the integration of spatial relationships in the image-based data representation, enhances the model’s performance when dealing with incomplete datasets.
- (1)
- The autoencoder achieves strong reconstruction performance under different levels of data masking. Under 10% masking, the model attains an MSE of 0.0012 and an SSIM of 0.96. Even with 30% masking, it maintains acceptable reconstruction accuracy, with an MSE of 0.0036 and an SSIM of 0.88.
- (2)
- The proposed framework outperforms benchmark methods, including ACI 318 and Eurocode 2. For 10% masking, it achieves (R2 = 0.94) and (NSEI = 0.93), whereas ACI 318 yields (R2 = 0.80) and Eurocode 2 yields (R2 = 0.78). Even under 30% masking, its (R2) remains at 0.85, highlighting its robustness.
- (3)
- Compared with traditional methods, the proposed approach exhibits lower prediction errors. For 10% masking, it achieves an MAE of 0.05 and an RMSE of 0.06, clearly outperforming ACI 318 (MAE = 0.12, RMSE = 0.14) and Eurocode 2 (MAE = 0.14, RMSE = 0.16).
- (4)
- The framework performs consistently across different data masking levels (10%, 20%, 30%) and effectively captures both local and global structural patterns. The integration of the attention mechanism enhances its ability to focus on critical features, improving its scalability and applicability to real-world structural scenarios.
- (5)
- From an engineering application perspective, the proposed framework can serve as a useful complement to existing code formulas (such as ACI 318 and Eurocode 2) for the rapid assessment of the shear capacity of slender beams without shear reinforcement within the experimental parameter range. It is particularly suitable for cases where design information is incomplete or inspection data for existing structures are missing. It is recommended that, in practical design, the predictions from this method be compared with code-based calculations, and a slightly conservative envelope of the two be adopted as the design basis. When engineering conditions clearly fall outside the ranges of geometric and material parameters covered by the database in this study, direct extrapolation should be avoided, and the method should only be used after introducing additional safety factors or conducting further experimental verification.
Author Contributions
Conceptualization, X.T.; methodology, X.T.; software, M.L.; validation, M.L. and Y.D.; formal analysis, M.L.; investigation, X.T.; resources, M.L.; data curation, X.T.; writing—review and editing, Y.D.; visualization, N.L.; supervision, N.L.; project administration, N.L. and Y.D.; funding acquisition, M.L. and N.L. All authors have read and agreed to the published version of the manuscript.
Funding
It was funded by the University-Industry Collaborative Horizontal Project between University of South China and Xi’an University of Science and Technology (Grant No. 6125HX141), the General Project of Humanities and Social Sciences of the Ministry of Education of China, titled “Investigation and Research on Productive Landscape Heritage of Beautiful Villages in Inner Mongolia” (Grant No. 24YJA760062). Finally, it was supported by Key Laboratory of Green and Low-Carbon Development of Oil and Coal Resources in Western Regions Open Research Fund (Project Approval No. SKLCRKF22-04).
Data Availability Statement
The original contributions presented in this study are included in the article. Further inquiries can be directed to the corresponding author.
Conflicts of Interest
Author Yongchao Dang was employed by the company Huangling Mining Group Co., Ltd. The remaining authors declare that the research was conducted in the absence of any commercial or financial relationships that could be construed as a potential conflict of interest.
References
- Kuo, W.W.; Hsu, T.T.; Hwang, S.J. Shear Strength of Reinforced Concrete Beams. ACI Struct. J. 2014, 111, 809–818. [Google Scholar] [CrossRef] [Scilit]
- Mansour, M.Y.; Dicleli, M.U.R.A.T.; Lee, J.Y.; Zhang, J.J.E.S. Predicting the shear strength of reinforced concrete beams using artificial neural networks. Eng. Struct. 2004, 26, 781–799. [Google Scholar] [CrossRef] [Scilit]
- Ni, X.; Cao, S.; Li, Y.; Jing, D. Shear strength prediction of reinforced concrete walls. Struct. Des. Tall Spec. Build. 2019, 28, e1599. [Google Scholar] [CrossRef] [Scilit]
- Chen, G.; Yang, Y.; Meng, X.; Chong, Y.; Shi, W.; Jin, J.; Bian, S.; Wu, J.; Yue, D. Seismic characterization of a landslide dam failure hazard chain: Insights into flow dynamics and implications for warning. Eng. Geol. 2022, 309, 106852. [Google Scholar] [CrossRef] [Scilit]
- Jeon, J.S.; Shafieezadeh, A.; DesRoches, R. Statistical models for shear strength of RC beam-column joints using machine-learning techniques. Earthq. Eng. Struct. Dyn. 2014, 43, 2075–2095. [Google Scholar] [CrossRef] [Scilit]
- Choi, K.K.; Hong-Gun, P.; Wight, J.K. Unified shear strength model for reinforced concrete beams-Part I: Development. ACI Struct. J. 2007, 104, 142. [Google Scholar]
- ACI 318-19; Building Code Requirements for Structural Concrete and Commentary. American Concrete Institute: Farmington Hills, MI, USA, 2019.
- Zsutty, T.C. Beam shear strength prediction by analysis of existing data. In Journal Proceedings; ACI: Farmington Hills, MI, USA, 1968; Volume 65, pp. 943–951. [Google Scholar]
- Niwa, J.; Yamada, K.; Yokozawa, K.; Okamura, H. Revaluation of the equation for shear strength of reinforced concrete beams without web reinforcement. Doboku Gakkai Ronbunshu 1986, 1986, 167–176. [Google Scholar] [CrossRef] [Scilit]
- Sarsam, K.F.; Al-Musawi, J.M. Shear design of high-and normal strength concrete beams with web reinforcement. Struct. J. 1992, 89, 658–664. [Google Scholar]
- Zararis, P.D.; Papadakis, G.C. Diagonal shear failure and size effect in RC beams without web reinforcement. J. Struct. Eng. 2001, 127, 733–742. [Google Scholar] [CrossRef] [Scilit]
- Tureyen, A.K.; Frosch, R.J. Concrete shear strength: Another perspective. Struct. J. 2003, 100, 609–615. [Google Scholar]
- Gan, D.; Zhou, Z.; Yan, F.; Zhou, X. Shear transfer capacity of composite sections in steel tubed-reinforced-concrete frames. Structures 2017, 12, 54–63. [Google Scholar] [CrossRef] [Scilit]
- Xu, T.; Castel, A.; Gilbert, R.I. On the reliability of serviceability calculations for flexural cracked reinforced concrete beams. Structures 2018, 13, 201–212. [Google Scholar] [CrossRef] [Scilit]
- Elchalakani, M.; Karrech, A.; Dong, M.; Ali, M.M.; Yang, B. Experiments and finite element analysis of GFRP reinforced geopolymer concrete rectangular columns subjected to concentric and eccentric axial loading. Structures 2018, 14, 273–289. [Google Scholar] [CrossRef] [Scilit]
- EN 1992-1-1; Eurocode 2: Design of Concrete Structures—Part 1-1: General Rules and Rules for Buildings. British Standard Institution: London, UK, 2004; p. 37.
- Hwang, S.J.; Lee, H.J. Strength prediction for discontinuity regions by softened strut-and-tie model. J. Struct. Eng. 2002, 128, 1519–1526. [Google Scholar] [CrossRef] [Scilit]
- Ismail, K.S.; Guadagnini, M.; Pilakoutas, K. Strut-and-tie modeling of reinforced concrete deep beams. J. Struct. Eng. 2018, 144, 04017216. [Google Scholar] [CrossRef] [Scilit]
- Ni, X.; Xiong, Q.; Kong, Q.; Yuan, C. Deep HystereticNet to predict hysteretic performance of RC columns against cyclic loading. Eng. Struct. 2022, 273, 115103. [Google Scholar] [CrossRef] [Scilit]
- Feng, D.C.; Wang, W.J.; Mangalathu, S.; Taciroglu, E. Interpretable XGBoost-SHAP machine-learning model for shear strength prediction of squat RC walls. J. Struct. Eng. 2021, 147, 04021173. [Google Scholar] [CrossRef] [Scilit]
- Liu, P.; Wang, L.; Ranjan, R.; He, G.; Zhao, L. A survey on active deep learning: From model driven to data driven. ACM Comput. Surv. 2022, 54, 1–34. [Google Scholar] [CrossRef] [Scilit]
- Khan, A.; Sohail, A.; Zahoora, U.; Qureshi, A.S. A survey of the recent architectures of deep convolutional neural networks. Artif. Intell. Rev. 2020, 53, 5455–5516. [Google Scholar] [CrossRef] [Scilit]
- Malekloo, A.; Ozer, E.; AlHamaydeh, M.; Girolami, M. Machine learning and structural health monitoring overview with emerging technology and high-dimensional data source highlights. Struct. Health Monit. 2022, 21, 1906–1955. [Google Scholar] [CrossRef] [Scilit]
- Mostafa, K.; Hegazy, T. Review of image-based analysis and applications in construction. Autom. Constr. 2021, 122, 103516. [Google Scholar] [CrossRef] [Scilit]
- Cang, R.; Li, H.; Yao, H.; Jiao, Y.; Ren, Y. Improving direct physical properties prediction of heterogeneous materials from imaging data via convolutional neural network and a morphology-aware generative model. Comput. Mater. Sci. 2018, 150, 212–221. [Google Scholar] [CrossRef] [Scilit]
- Soibelman, L.; Kim, H. Data preparation process for construction knowledge generation through knowledge discovery in databases. J. Comput. Civ. Eng. 2002, 16, 39–48. [Google Scholar] [CrossRef] [Scilit]
- Sandeep, M.S.; Tiprak, K.; Kaewunruen, S.; Pheinsusom, P.; Pansuk, W. Shear strength prediction of reinforced concrete beams using machine learning. Structures 2023, 47, 1196–1211. [Google Scholar] [CrossRef] [Scilit]
- Rahman, J.; Ahmed, K.S.; Khan, N.I.; Islam, K.; Mangalathu, S. Data-driven shear strength prediction of steel fiber reinforced concrete beams using machine learning approach. Eng. Struct. 2021, 233, 111743. [Google Scholar] [CrossRef] [Scilit]
- Yaseen, Z.M. Machine learning models development for shear strength prediction of reinforced concrete beam: A comparative study. Sci. Rep. 2023, 13, 1723. [Google Scholar] [CrossRef] [Scilit]
- Abuodeh, O.R.; Abdalla, J.A.; Hawileh, R.A. Prediction of shear strength and behavior of RC beams strengthened with externally bonded FRP sheets using machine learning techniques. Compos. Struct. 2020, 234, 111698. [Google Scholar] [CrossRef] [Scilit]
- Anvari, A.T.; Babanajad, S.; Gandomi, A.H. Data-driven prediction models for total shear strength of reinforced concrete beams with fiber reinforced polymers using an evolutionary machine learning approach. Eng. Struct. 2023, 276, 115292. [Google Scholar] [CrossRef] [Scilit]
- Zhang, S.; Lai, X.; Cao, J.; Xu, H.; Zhang, Y.; Yan, B.; Ji, S. Theoretical analyses of surrounding rock stress of a non-circular tunnel considering the horizontal inclination of initial principal stress field. Tunn. Undergr. Space Technol. 2025, 167, 106994. [Google Scholar] [CrossRef] [Scilit]
- Jayasinghe, T.; Chen, B.W.; Zhang, Z.; Meng, X.; Li, Y.; Gunawardena, T.; Mangalathu, S.; Mendis, P. Data-driven shear strength predictions of recycled aggregate concrete beams with/without shear reinforcement by applying machine learning approaches. Constr. Build. Mater. 2023, 387, 131604. [Google Scholar] [CrossRef] [Scilit]
- Alshboul, O.; Almasabha, G.; Shehadeh, A.; Mamlook, R.E.A.; Almuflih, A.S.; Almakayeel, N. Machine learning-based model for predicting the shear strength of slender reinforced concrete beams without stirrups. Buildings 2022, 12, 1166. [Google Scholar] [CrossRef] [Scilit]
- Fu, B.; Feng, D.C. A machine learning-based time-dependent shear strength model for corroded reinforced concrete beams. J. Build. Eng. 2021, 36, 102118. [Google Scholar] [CrossRef] [Scilit]
- Chou, J.S.; Pham, T.P.T.; Nguyen, T.K.; Pham, A.D.; Ngo, N.T. Shear strength prediction of reinforced concrete beams by baseline, ensemble, and hybrid machine learning models. Soft Comput. 2020, 24, 3393–3411. [Google Scholar] [CrossRef] [Scilit]
- Feng, D.C.; Wang, W.J.; Mangalathu, S.; Hu, G.; Wu, T. Implementing ensemble learning methods to predict the shear strength of RC deep beams with/without web reinforcements. Eng. Struct. 2021, 235, 111979. [Google Scholar] [CrossRef] [Scilit]
- Liguori, A.; Markovic, R.; Dam, T.T.H.; Frisch, J.; van Treeck, C.; Causone, F. Indoor environment data time-series reconstruction using autoencoder neural networks. Build. Environ. 2021, 191, 107623. [Google Scholar] [CrossRef] [Scilit]
- Ismail, K.S. Shear Behaviour of Reinforced Concrete Deep Beams. Ph.D. Thesis, University of Sheffield, Sheffield, UK, 2016. [Google Scholar]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.