
 Open Access
- Technical Note

15 Pages
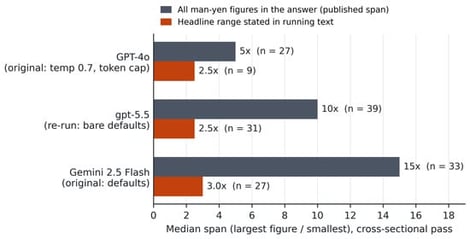
Consumers facing home-renovation quotes operate in a credence-goods market: they cannot verify whether a quoted price is fair, and general-purpose large language models (LLMs) are now a zero-cost place to ask. Whether LLM answers are actionable for this purpose is untested. Demand-side benchmarks exist for medical, legal, and financial advice, but not for construction costs. We present, to our knowledge, the first consumer-question benchmark for construction costs: a fixed public question set with public scoring rules that characterizes answer properties, not a comparison against ground-truth prices. Forty Japanese renovation-price questions were posed to frontier LLMs, with repeated-trial sets measuring output stability. A matched re-run at bare provider defaults with a current frontier model (GPT-5.5) removes a settings confound in the original configuration. We separate two quantities. The headline range that a model states as the going rate has a median width of 2.5× to 3×. The full set of price figures in the same answer, including itemized components and unit rates, spans a median of 10× at bare defaults; this is the dispersion a reader must integrate. No LLM answer volunteered an over-charge decision threshold, although no question asked for one. Across five repeated runs, the headline range of GPT-5.5 stayed within 1.5× on 15 of 20 everyday questions, while on the widest questions, its endpoints moved by up to 5×. A deterministic structured engine over an open cost database is included as existence proof that a citable reference layer is constructible; its accuracy is not validated here. All questions, raw outputs, harnesses, and scoring codes are public.
Intell. Infrastruct. Constr.
16 October 2026