


Abstract
Graph representation learning (GRL) has emerged as a unifying paradigm for modeling the relational and heterogeneous nature of battery energy storage systems (BESS), yet a systematic synthesis focused on data-scarce (few-shot) battery scenarios is still lacking. Graph representation learning offers a natural way to describe the structure and interaction of battery cells, modules and packs. At the same time, battery applications often suffer from very limited labeled data, especially for new chemistries, extreme operating conditions and second-life use. This review analyzes how graph representation learning can be combined with few-shot learning to support key battery management tasks under such data-scarce conditions. We first introduce the basic ideas of graph representation learning, including models based on neighborhood aggregation, contrastive learning, autoencoders and transfer learning, and discuss typical data, model and algorithm challenges in few-shot scenarios. We then connect these methods to battery state estimation problems, covering state of charge, state of health, remaining useful life and capacity. Particular attention is given to approaches that use graph neural models, meta-learning, semi-supervised and self-supervised learning, Bayesian deep networks, and federated learning to extract transferable features from early-cycle data, partial charge–discharge curves and large unlabeled field datasets. Reported studies show that, with only a small fraction of labeled samples or a few initial cycles, these methods can achieve state and life prediction errors that are comparable to or better than conventional models trained on full datasets, while also improving robustness and, in some cases, providing uncertainty estimates. Based on this evidence, we summarize the main technical routes for few-shot battery scenarios and identify open problems in data preparation, cross-domain generalization, uncertainty quantification and deployment on real battery management systems. The review concludes with a research outlook, highlighting the need for pack-level graph models, physics-guided and probabilistic learning, and unified benchmarks to advance reliable graph-based few-shot methods for next-generation intelligent battery management.
1. Introduction of Graph Representation Learning
Graph representation learning [1,2,3] has emerged as a prominent research direction within machine learning, finding extensive applications in areas such as social network analysis [4,5], recommendation systems [6,7], battery energy management [8,9], and life sciences [10,11]. Unlike traditional machine learning approaches, which typically assume that data instances are independently and identically distributed, many real-world problems are inherently relational and characterized by complex graph structures where the interactions among nodes play a crucial role. For example, in battery modules, each cell can be modeled as a node, and graph representation learning enables the extraction of informative embeddings that capture the attributes and relationships of individual cells. Figure 1 provides an overview of representative application domains of graph representation learning, highlighting its role in fields ranging from social networks to bioinformatics. The framework of graph representation learning is exhibited in Figure 2. Consequently, developing effective methods to learn representations of nodes, edges, and subgraphs, which are commonly referred to as graph embeddings, has become an important and challenging research problem.
Figure 1.
Applications of graph representation learning [12].
Figure 2.
The framework of graph representation learning. The graph structure is encoded into embeddings, which are used to perform tasks at the node, edge, or graph level.
To enhance the effectiveness of graph-based models in data-scarce scenarios, recent studies have explored the integration of graph representation learning with few-shot learning. Graph representation learning combined with few-shot learning [13,14,15,16] aims to extract effective graph representations from limited labeled data to support downstream tasks such as node classification, graph classification, and link prediction. Few-shot learning [17,18,19] refers to scenarios in which the available labeled samples are extremely scarce. In practice, data collection is often constrained by human resources, material costs, time constraints, and the intrinsic rarity of certain types of data [20,21]. For example, in the field of medical image diagnosis, annotations require the expertise of qualified professionals, making the process time-consuming, labor-intensive, and expensive, which limits the amount of labeled data that can be obtained [22,23]. Similarly, in the monitoring and conservation of endangered species, the scarcity of target populations and the inherent difficulty of observation result in a severe shortage of relevant sample data. Under such conditions, conventional machine learning and deep learning methods tend to suffer from overfitting [24], inefficient computation, and an inability to effectively integrate graph structures with node and edge attributes. Addressing these challenges and developing robust graph representation learning approaches that can perform well in few-shot settings has become an important research objective [24,25].
1.1. Combination of Graph Neural Networks and Meta-Learning
In recent years, the combination of Graph Neural Networks (GNNs) and meta-learning has emerged as a promising approach to address the challenges posed by limited labeled data in graph-based tasks. GNNs learn node representations by propagating and aggregating information across neighboring nodes [26,27,28]. However, when the available training data is extremely limited, conventional GNNs often struggle to achieve satisfactory performance [29,30]. The central objective of meta-learning is to enhance a model’s learning efficiency and adaptability, enabling it to rapidly generalize to new tasks by leveraging prior experience [31,32]. Meta-learning methods offer a promising avenue to address this challenge [33]. Their primary advantage lies in enabling models to rapidly adapt to new tasks by leveraging knowledge acquired from previous experiences, much like how humans learn new skills. A growing body of research is exploring how meta-learning can be integrated with GNNs to allow models to learn effectively from only a small number of labeled examples [34,35,36]. Model-Agnostic Meta-Learning (MAML) is a representative meta-learning algorithm that trains over multiple tasks to identify a parameter initialization that is broadly suitable across tasks [37,38]. With such initialization, the model can quickly adapt to a new task using only a few labeled samples. However, this approach primarily relies on supervised signals and tends to overlook the valuable information hidden in unlabeled data, such as underlying data distributions and inter-class relationships [39]. GraphMeta, for example, is a meta-learning framework specifically designed for graph-structured data [6]. It captures shared patterns across diverse graph learning tasks to improve performance in few-shot scenarios. Zhou et al. [36] introduced Meta-GNN, which combines meta-learning with graph convolutional networks. By leveraging multi-task training and task transfer, Meta-GCN enhances the model’s capability to generalize from limited labeled data.
Nevertheless, these methods often involve computationally intensive multi-task optimization procedures. In resource-constrained environments, such as mobile devices and embedded systems, their high computational overhead can lead to latency issues, making it difficult to meet real-time requirements in few-shot detection tasks [40,41,42]. Researchers have proposed various meta-learning strategies to train GNNs under different conditions, and these approaches have been applied across multiple domains. In social networks, where only a small portion of user labels are available, meta-learning enables models to quickly adapt to new user classification tasks. Similarly, in molecular graph representation learning for drug discovery, where labeled data is often scarce, combining GNNs with meta-learning allows models to effectively learn predictive representations from only a limited set of annotated molecular graphs [43,44].
1.2. Graph Contrastive Learning
Alongside meta-learning strategies, contrastive learning has become another powerful technique for enhancing graph representation learning under data scarcity. Graph contrastive learning enables models to construct pairs of “similar” and “dissimilar” samples and learn feature representations by comparing their differences [45,46,47]. This approach is particularly well-suited to scenarios with limited labeled data [45,48]. However, most existing graph contrastive learning methods primarily focus on structural information within the network, often neglecting the semantic content encoded in node attributes or edge features [49,50], such as textual descriptions or other properties. Relying solely on structural similarity for contrastive training can limit the model’s ability to capture complex semantic relationships present in graph data [51,52].
Traditional graph embedding methods often simulate random walks over the graph structure to generate node sequences, enabling models to learn the underlying patterns of these paths and derive feature vectors for each node [53,54]. In user–item interaction graphs from social media platforms or ecommerce websites, such embedding techniques help models uncover hidden associations between user preferences and product attributes, thereby supporting recommendation systems. Wu et al. [55] proposed a novel graph contrastive learning approach that enhances the expressiveness of learned representations by contrasting feature distributions across different graphs. This method alleviates the challenges posed by insufficient labeled data in graph learning tasks.
1.3. Graph Autoencoders
Graph autoencoders are effective tools for capturing both the structural and attribute information inherent in graph data. In few-shot scenarios, they encode node, edge, and subgraph information into low-dimensional vector representations through an encoder [56,57,58], and then reconstruct the original graph structure via a decoder [59,60]. This process enables the model to uncover critical feature patterns hidden in limited data, providing more informative and discriminative representations for downstream tasks. This approach has also been applied in drug discovery, where graph autoencoders are used to generate novel molecular graphs to augment datasets and improve model training performance. In bioinformatics, for example, graph autoencoders can enhance classification accuracy when predicting the functions of protein nodes in protein–protein interaction networks with scarce labeled samples [61,62]. In social networks, autoencoders can generate new synthetic graph samples based on observed structures to enrich training data [63,64]. When user–item interaction data are limited, such models can learn embeddings for users and products, supporting more accurate link prediction and personalized recommendations. For few-shot link prediction tasks, graph autoencoders learn node embeddings from sparse connectivity patterns and estimate the likelihood of edge formation between node pairs. Similarly, in anomaly detection for graph data, autoencoders establish a baseline by learning how normal graphs are encoded and reconstructed [65,66]; deviations in reconstruction error can then be used to identify abnormal nodes or edges. For example, in small-scale network traffic graphs, this enables detection of rare anomalous traffic patterns to enhance security.
However, this approach also has certain limitations. When the available data is extremely limited, graph autoencoders may struggle to accurately reconstruct the true underlying structure of the graph. For example, in drug development, the generated molecular structures may deviate from actual compounds, potentially limiting their utility [67]. Similarly, when creating synthetic graph samples in social networks, the reconstructed graphs may fail to reflect real social relationships accurately, which can ultimately reduce the effectiveness of recommendation systems.
1.4. Transfer Learning
Figure 3 illustrates a typical pipeline for transfer learning-based long-term feature extraction. In this framework, transfer learning provides a mechanism for reusing knowledge from data-rich domains to enhance learning in data-poor settings. Transfer learning addresses the problem of data scarcity in few-shot learning by transferring knowledge acquired in a source domain to improve performance in a target domain [67,68,69]. In the context of graph representation learning, transfer learning enables models to leverage information learned from large-scale graph datasets and apply it to tasks where only limited labeled data are available, thereby reducing reliance on extensive annotation [70]. In practice, this approach has demonstrated strong effectiveness. For example, in drug discovery, researchers can pre-train models on a large corpus of known molecular graphs and then adapt these models to predict properties of new compounds with only a small number of labeled examples [71,72]. By reusing previously acquired knowledge, transfer learning allows models to rapidly adapt to new scenarios without having to learn tasks entirely from scratch. This not only reduces the amount of required data but also increases the practical value and generalization capability of the models.
Figure 3.
Flowchart of long-term feature extraction based on transfer learning. The process begins with a frozen VGG16 model pre-trained on the ImageNet dataset, used to extract generic features. These features are then passed through fully connected and dropout layers for initial output generation. Subsequently, fine-tuning is performed on the top layers of the VGG16 model along with the classifier, enabling domain-specific adaptation with limited labeled data [73].
Recent efforts have explored how transfer learning can be effectively implemented through pre-trained graph neural architectures to address few-shot learning challenges in graph-structured data. Graph convolutional networks (GCNs) have demonstrated strong capabilities in learning effective node embeddings [74,75]. Zhang et al. [76] showed that in few-shot scenarios, pre-trained GCN models can significantly improve transfer learning performance on small graph datasets. Zhu et al. [77] proposed that graph attention networks (GATs) can effectively learn graph representations under few-shot conditions by leveraging pre-training. Gats incorporate a self-attention mechanism that assigns different weights to neighboring nodes according to their importance, making them particularly suitable for learning from limited data. GRAPHSAGE, as illustrated in Figure 4, generates node embeddings by sampling and aggregating features from neighboring nodes [77,78,79]. Collectively, these studies highlight that combining transfer learning with pre-training and graph representation learning methods has substantially alleviated the challenges associated with few-shot applications and reduced the reliance on extensive labeled data. A unified overview of these representative strategies is illustrated in Figure 5. However, operations such as neighbor sampling and feature aggregation in GRAPHSAGE, as well as self-attention computation in gats, introduce considerable computational overhead. When the graph scale increases, the resource consumption and processing time escalate rapidly, making it difficult to meet the demands of real-time applications. In time-sensitive systems such as online recommendation platforms, this computational complexity can lead to response delays when processing few-shot graph data.
Figure 4.
The basic framework of GRAPHSAGE. (a) Sample neighborhood, (b) Aggregate feature information from neighbors, (c) Predict graph context and label using aggregated information. It samples a fixed-size set of neighbors from different hop levels, aggregates their feature information through a neighborhood aggregation function, and learns node embeddings in an inductive manner to support downstream tasks such as node classification [78,79].
Figure 5.
Taxonomy and representative methods of graph representation learning under few-shot conditions, including meta-learning, contrastive learning, graph autoencoders, and transfer learning [61,80].
To put the above developments into the context of battery research, this review specifically focuses on graph representation learning under data-scarce conditions for battery energy systems. Our primary objective is to systematically summarize how GRL has been applied to key battery management tasks—such as SOC, SOH, RUL and degradation trajectory prediction—when only limited labeled data are available, and to critically compare GRL-based approaches with both traditional physics-based models (e.g., ECMs with Kalman filtering) and non-graph deep learning methods (e.g., CNNs, RNNs, TCNs and attention-based architectures). Particular emphasis is placed on understanding in which scenarios graph-centric models offer tangible advantages in terms of data efficiency, robustness and interpretability, and where their added complexity may not yet be justified.
Building on this motivation, the remainder of the paper is organized as follows. Section 2 discusses the theoretical and technical foundations of few-shot learning on graphs, including data-, model- and algorithm-level challenges and corresponding solution strategies. Section 3 turns to battery applications and reviews GRL-based methods for SOC/SOH/RUL estimation and degradation modeling, together with closely related advanced learning paradigms such as meta-learning, semi- and self-supervised learning, Bayesian deep networks, transfer and federated learning. Section 4 provides an integrated discussion of methodological issues in data preparation, cross-domain generalization and uncertainty quantification, and outlines open problems and future research directions toward reliable graph-based few-shot battery management.
2. Theoretical and Technical Foundations
2.1. Challenges in Few-Shot Learning
2.1.1. Data-Level Challenges
(1) Data Sparsity and Incompleteness
In few-shot learning scenarios, the issues of data sparsity and incompleteness in graph-structured data are particularly pronounced. Due to the limited number of samples, it becomes challenging for the observed node connections in a graph to comprehensively capture the underlying complex relationships [77]. A representative example can be found in drug discovery. In studies of molecular interactions, small-sample datasets may contain only a few known drug–drug or drug–target interactions [81,82,83]. However, many potential interactions remain unrecorded due to data scarcity. This lack of coverage results in the loss of critical relational information, making it difficult for models to accurately infer the true dependencies among entities. A similar problem arises in the construction of knowledge graphs. When only limited data are available, many relationships between entities are omitted, leading to sparsely connected knowledge graphs. Such incomplete structures hinder the ability to support reasoning and decision-making tasks that rely on the knowledge graph framework.
(2) Data Noise and Quality Issues
Another major challenge in graph-based few-shot learning lies in data noise and annotation inconsistencies, which can significantly distort the learning process and degrade model reliability. In few-shot settings, limited data availability often amplifies the impact of noise and reduces overall data quality [84,85]. During the data collection process, even minor oversights can introduce bias. This issue is particularly evident in social network analysis, where anomalous behavior from a few highly active users can disproportionately influence the model’s learning process. Moreover, inconsistencies in data annotation are common, as annotators may rely on subjective standards, leading to divergent labeling results. Inaccuracies in graph-structured data, whether in node features or edge connections, introduce structural misconceptions for learning models. This impedes the effective discovery of genuine underlying patterns, consequently degrading both predictive accuracy and model robustness.
(3) Distribution Shift and Domain Adaptation
A further obstacle in graph-based few-shot learning arises from distributional bias and domain shift, which undermine the model capacity to generalize across diverse tasks and datasets. When sample sizes are limited, the available data may fail to reflect the true underlying distribution, leading to significant distributional bias [86]. This issue becomes more critical when models are applied across different domains, where discrepancies between the source and target data further complicate the learning process. In graph-structured image classification tasks, insufficient training data may only cover a subset of categories and features, resulting in models that generalize poorly in real-world applications. Similarly, in transfer learning, applying a model trained on large-scale graph data to a new domain with limited samples often proves ineffective [86]. This is because the structural properties, node features, and edge connectivity patterns may differ significantly between domains, making it difficult for the pretrained model to adapt without additional fine-tuning or alignment mechanisms.
2.1.2. Model-Level Challenges
(1) Overfitting
When training data are limited, models are highly susceptible to noise and spurious correlations. GNNs, in particular, often involve a large number of parameters. In data-scarce settings, these models tend to memorize specific patterns in the training graphs rather than learning generalizable representations. For example, in node classification tasks, the model may over-rely on particular connectivity patterns that are unique to the training nodes [87]. However, such patterns may not appear in the test data, leading to poor generalization performance and reduced accuracy in unseen scenarios.
(2) Insufficient Representational Capacity
Small-sample datasets often fail to capture the full range of data variations and underlying complexity, which limits the model’s ability to learn expressive representations. When training data are scarce, GNNs struggle to extract complete feature information, making it difficult to learn meaningful patterns of node attributes and edge connectivity. In graph classification tasks, for example, limited training samples may only include simple connectivity motifs. Consequently, the model fails to recognize more complex structures, resulting in incomplete feature representations and high error rates when applied to new, unseen data.
(3) Challenges in Model Architecture Design and Optimization
In few-shot scenarios, conventional GNN architectures may no longer be suitable, necessitating the design of models specifically tailored for few-shot learning. Overly complex models tend to memorize training details without generalizing well, while overly simple models often lack the capacity to capture sufficient features [88,89]. For instance, deep networks, though effective on large datasets, are prone to vanishing or exploding gradients when trained on small data, which hinders proper convergence. Moreover, standard optimization algorithms like stochastic gradient descent (SGD) are more likely to get trapped in local minima in low-data regimes, preventing the model from reaching optimal parameter configurations [90,91]. Thus, designing lightweight yet expressive model architectures, along with appropriate optimization strategies, remains a critical challenge for effective graph representation learning under few-shot conditions.
2.1.3. Algorithm-Level Challenges
(1) Limitations of Data Augmentation Techniques
Data augmentation is a widely adopted strategy to alleviate the challenges posed by small-sample datasets. However, in the context of graph data, existing augmentation methods face several inherent limitations [92]. For image data, common augmentations such as rotation, flipping, and cropping are straightforward to implement [93,94]. In contrast, the structural and semantic complexity of graph data makes augmentation more difficult and error-prone. Current graph augmentation techniques mainly involve edge perturbation and node feature modification [95]. However, such operations can unintentionally distort the graph’s semantic structure [96,97]. For example, randomly adding or removing edges may alter the underlying connectivity patterns between nodes, leading the model to learn incorrect feature representations [98]. Moreover, most existing graph augmentation approaches are heuristic in nature and lack theoretical justification, making it uncertain whether the augmented data will effectively improve model performance [99,100]. Designing more principled and effective graph augmentation strategies that preserve the semantic integrity of the graph while increasing data diversity remains a core challenge in few-shot graph representation learning.
(2) Challenges in Combining Meta-Learning with Few-Shot Graph Representation Learning
Meta-learning offers a promising paradigm for enabling models to quickly adapt to new tasks using only a small amount of data, making it a potential solution for few-shot graph learning [101,102]. However, applying meta-learning to graph-structured data presents several practical challenges. Graphs often exhibit diverse and complex topologies, and task-specific graphs may differ significantly in their node distributions and connectivity patterns. This structural heterogeneity makes it difficult for meta-learning algorithms to extract generalizable patterns across tasks—similar to attempting to find universal characteristics across the traffic networks of different cities, each with a unique layout. Furthermore, meta-learning typically requires access to a large number of task instances to train effectively, which contradicts the few-shot assumption where task data are inherently limited [103,104]. Therefore, it remains an open problem to develop methods that can seamlessly incorporate meta-learning principles into the architectural and training design of graph neural networks. Achieving such integration is key to enhancing the adaptability and effectiveness of graph representation learning in low-data regimes.
2.2. Solutions for Graph Representation Learning
2.2.1. Data Augmentation Approaches
When training data are limited, data augmentation offers an effective means of increasing the sample size. This strategy is particularly well-suited for graph data, as various transformations can be applied to the original graph structures to generate new samples. Specifically, one can modify the graph topology by randomly adding or removing edges, or slightly perturbing node feature values. It is also possible to extract subgraphs from larger graphs to serve as additional training instances. For example, in molecular graphs used in chemistry, researchers often augment data by rotating molecular structures or altering atomic positions to create new variants. Although these operations are relatively simple, they significantly enhance data diversity.
In battery applications, it is also important to mitigate the risk that augmented samples become physically unrealistic or inconsistent with actual aging behavior. First, augmentation operations should be constrained by basic electrochemical and operational knowledge, for example by enforcing consistency with voltage–SOC relationships, capacity limits and reasonable degradation trends, and by discarding samples that violate fundamental physical or safety constraints. Second, augmented data should be validated against held-out real measurements, for instance by checking whether models trained with augmented samples can still reproduce realistic distributions and degradation patterns, and whether their performance on purely real test sets does not deteriorate. Third, robust or uncertainty-aware models—such as architectures equipped with outlier detection or confidence estimation—can further reduce the influence of potentially unrealistic augmented samples by down-weighting or rejecting them during training and inference.
2.2.2. Model Design and Optimization Methods
To address the risk of overfitting caused by limited data, model architectures should be kept as simple as possible. Lightweight models with fewer parameters are generally more suitable for few-shot scenarios, as they reduce the likelihood of overfitting. For small-sample graph classification tasks, shallow graph convolutional networks (GCNs) can be employed in place of deep, stacked architectures. In addition, regularization techniques such as L1 or L2 penalties can be used to constrain model parameter magnitudes, thereby promoting sparsity or preventing excessive weight growth [105,106]. Dropout, which randomly masks parts of the node or edge information during training, helps prevent the model from relying too heavily on specific features and further enhances its generalization ability [107]. These techniques can significantly reduce the number of parameters and computational cost, making GNN-based models more suitable for deployment on embedded or edge devices. However, aggressive simplification may degrade performance if not carefully designed.
It is important to emphasize that such model simplification strategies are not universally appropriate for all systems. For battery energy storage representations in particular, overly aggressive simplification may remove critical spatial–temporal coupling patterns, such as thermal and electrical interactions between cells or modules, local imbalance, and early signatures of abnormal degradation. Therefore, simplification should be treated as a task- and system-dependent design choice: it is more suitable for coarse-grained objectives (e.g., pack-level power dispatch or high-level fleet management) or for embedded BMS deployment with clearly defined operating conditions, where reduced-order or coarser-grained graph models have been validated against higher-fidelity references. For fine-grained cell-level diagnostics and safety-critical functions, however, full-fidelity or only gently simplified models, ideally combined with physical regularization and uncertainty estimation, are generally preferable.
2.2.3. Integration of Meta-Learning and Transfer Learning Approaches
Meta-learning enables models to rapidly adapt to new tasks by learning how to update their parameters efficiently across a range of small-scale tasks [108]. This enables the model to generalize fast with a small number of examples. In graph-based problems, a powerful technique is to pretrain a GNN first on massive, general- purpose graph datasets, enabling the model to learn generic structural and feature-level patterns. Subsequently, the pre-trained model may be fine-tuned on a target few-shot data set in a particular domain to adapt to the specific properties of the new task. This not only alleviates the computation cost for training from scratch but also enhances the performance on few-shot tasks by borrowing the transferable knowledge from the relevant domains.
2.2.4. Enhanced Integration of Graph Structure and Attribute Information
To better integrate structural and attribute information in graph data, model designs can be improved to refine the message-passing mechanisms in graph neural networks. Specifically, during node representation updates, models can be designed to account not only for the connectivity patterns among neighboring nodes but also for their individual feature attributes [107]. Incorporating attention mechanisms further enhances this process by allowing the model to dynamically assess the importance of different types of information [109,110]. This enables the model to adjust its focus between structural and attribute cues based on the task requirements. In knowledge graph applications [111,112], for example, the model can adaptively decide whether to prioritize entity attributes or inter-entity relationships depending on the reasoning objective. Such flexibility contributes to more accurate inference and improves the overall performance of the model.
Table 1 shows a concise summary of the key challenges and corresponding technical solutions identified in recent research, serving as a reference for designing more robust and generalizable graph learning frameworks under data-scarce conditions.
Table 1.
Summary of Challenges and Corresponding Solutions in Few-Shot Graph Representation Learning.
3. Graph Representation Learning for Battery Management in Few-Shot Scenarios
3.1. Research Background
As the global energy structure shifts toward low-carbon and clean alternatives, lithium-ion batteries have emerged as the core power source for electric vehicles and energy storage systems due to their high energy density and long cycle life [113,114,115,116]. However, the issue of data scarcity throughout the battery life cycle has become increasingly prominent [80,117,118]. Battery Management System (BMS) is the key to stable, safe and efficient operation of new energy systems, where state estimation (such as SOC: State of Charge, SOH: State of Health) and remaining useful life (RUL) prediction are core tasks. With the large-scale application of electric vehicles and energy storage systems, BMS needs to achieve generalized and robust state estimation under multiple operating conditions, multiple aging stages, cross-platform and cross-chemistry systems. Health state estimation (SOC, SOH, RUL) and anomaly diagnosis/warning are core tasks. Battery systems possess inherent structural characteristics: cell–module–battery pack hierarchical architecture, series-parallel networking, spatial correlation of thermal/aging coupling, dependencies between different sensing points, as well as data domain differences across multiple vehicles/multiple operating conditions. These structural information are challenging to be adequately captured by simple one-dimensional time series models.
Traditionally, state estimation has relied on equivalent circuit models (ECMs) or simplified electrochemical models, combined with observers such as Kalman filters and their variants. These methods offer a certain level of physical interpretability, but their performance depends strongly on accurate parameter identification and modeling assumptions. They often struggle to capture the complex nonlinear degradation processes and cell-to-cell manufacturing variability observed in real applications.
Meanwhile, advances in sensing and data acquisition have enabled the collection of large amounts of voltage, current, temperature and capacity data in both laboratory cycling and field usage. This has opened the door for machine learning (ML) and deep learning (DL) methods to play an increasingly important role in battery state estimation. Recent works have moved from classical supervised learning regressors to modern DL architectures, including convolutional neural networks (CNNs), recurrent neural networks (RNNs), temporal convolutional networks (TCNs), attention mechanisms, graph neural networks (GNNs), transfer and meta-learning, semi- and self-supervised learning, as well as probabilistic ML with uncertainty quantification.
Thelen et al. [119] provided a comprehensive overview of probabilistic ML for battery health diagnostics and prognostics, emphasizing that cell-to-cell variability and time-varying operating conditions inherently introduce uncertainty in battery behavior, and that decisions based solely on point estimates can be misleading. Tang et al. [120] reviewed SOH estimation methods and health indicators, highlighting open challenges such as cross-condition generalization, label scarcity and the lack of standardized benchmarks. Liu et al. [121] surveyed deep learning-based SOC estimation approaches, pointing out both the significant performance gains and the practical challenges in real-world BMS deployment.
Figure 6 outlines the typical workflow for SOH estimation using ML algorithms, which generally comprises four stages: offline measurement, feature generation, model training, and model validation [122]. In the first stage, raw data—including current, voltage, temperature, and time—are acquired and recorded through offline experiments. Next, a set of k-dimensional health features is extracted from the original d-dimensional measurement data to capture key degradation patterns; The third stage involves training the ML model using the health features as inputs and SOH as the target output, while simultaneously optimizing and tuning the parameters of model. Finally, the trained model is validated and deployed to predict SOH. ML-based SOH prediction is highly efficient because it does not require explicit interpretation of the underlying electrochemical reactions occurring within lithium-ion batteries. Moreover, developers need not possess in-depth knowledge of battery materials or electrochemical properties. As advanced ML algorithms continue to evolve, estimation accuracy, generalization capability, learning performance, and convergence speed have all improved significantly. Data-driven methods (machine learning and deep learning) have achieved significant progress in recent years, particularly CNN/RNN (LSTM/GRU), autoencoders and attention mechanisms showing outstanding performance in time series modeling and feature extraction [123,124,125,126].
Figure 6.
Basic Workflow of Lithium-Ion Battery SOH Estimation Using Machine Learning/Deep Learning [122].
However, practical applications often face two severe constraints: (1) Data scarcity: Strictly controlled lifespan aging and full operating condition acquisition incur high costs, resulting in limited available labeled samples, especially under new battery chemistries, extreme temperatures, and current conditions. (2) Distribution drift and heterogeneity: Cells from different batches, manufacturers, or usage scenarios exhibit varied statistical properties, making the model prone to performance degradation during domain transfer. Traditional methods struggle to meet the high-precision demands of battery management in few-shot scenarios, presenting a unique opportunity for the application of graph representation learning techniques [113].
Graph Representation Learning (GRL) [127,128,129,130] models battery multi-source data and system structures as graphs, learning embedding representations of nodes, edges, and subgraphs. It is naturally suited for expressing coupling relationships within battery clusters (such as series-parallel topology, thermal/electrical interactions), multi-sensor fusion, and cross-sample similarity structures, and can be combined with metric learning and meta-learning to achieve knowledge transfer and rapid adaptation in few-shot scenarios. Therefore, integrating GRL into battery management tasks, especially under few-shot conditions, is expected to alleviate data scarcity and domain transfer difficulties, improving the estimation accuracy and stability of SOC/SOH/RUL.
Building on these overviews and a set of recent research articles that you provided, this work aims to present a structured and critical review of ML and DL methods for lithium-ion battery state estimation. We focus on SOH, SOC, RUL and online capacity estimation, organizing the discussion along three axes: (i) task and indicator definitions; (ii) methodological advances from classical ML to advanced DL architectures; and (iii) cross-cutting issues such as data preparation, generalization and uncertainty.
3.2. Fundamentals of Battery State Estimation
3.2.1. Key State Variables and Health Indicators
In the field of lithium-ion batteries (LIBs), in addition to internal variables such as concentration and temperature, battery performance-related variables are also crucial for their diagnosis and operation. The most commonly considered internal states and indicators include:
State of Charge (SOC), representing the ratio of the remaining charge to the nominal capacity.
State of Health (SOH), representing the level of degradation relative to a reference state (often initial or rated conditions).
Remaining Useful Life (RUL), representing the remaining time or cycles until a predefined end-of-life (EOL) criterion is reached.
Available capacity, representing the maximum deliverable capacity under current conditions.
Tang et al. [120] categorized health indicators into three main classes:
Capacity-based indicators: remaining capacity, capacity retention, available energy. These are intuitively linked to user-observed performance but usually require specific diagnostic cycles to measure precisely.
Impedance-based indicators: DC internal resistance, impedance at selected frequencies from electrochemical impedance spectroscopy (EIS), or pseudo-EIS features derived from current–voltage data. These indicators relate more directly to electrode, electrolyte and interfacial processes.
Curve feature-based indicators: features extracted from voltage–capacity curves, such as peaks and widths of dv/dq curves, capacities within specific voltage windows, or duration of certain constant-current/constant-voltage stages.
SOC estimation is usually based on instantaneous or short-term histories of voltage, current and temperature [121,131]. While SOC is not a direct measure of degradation, accurate SOC estimation is a prerequisite for monitoring usable range and preventing overcharge or deep discharge, both of which accelerate degradation.
SOH estimation [132], in contrast, algorithms may target any of these indicators, or combinations thereof. In recent DL-based works, multi-indicator inputs have been increasingly used. For example, in the MHATTCN network [133], capacity, internal resistance and curve-based features are jointly fed into a TCN with multi-head attention to estimate health states.
Thelen et al. [119] stressed that beyond these state variables and indicators, the uncertainty associated with their estimation is itself an essential quantity: uncertainty arises from manufacturing variability, measurement noise, model mismatch and unknown future operating conditions. Quantifying uncertainty is thus central to robust diagnostics and prognostics.
3.2.2. From Physics-Based Models to Data-Driven and Probabilistic Frameworks
Classical approaches to state estimation are based on physics-inspired models, such as ECMs or reduced-order electrochemical models, combined with Kalman filters or particle filters. These models yield interpretable parameters and can be informed by physical understanding of electrochemical processes. However, they often require substantial effort for parameter identification, may not capture complex aging mechanisms, and have limited ability to generalize across cell types and usage patterns.
Data-driven methods—ranging from classical ML regressors to DL architectures—flip the perspective: instead of explicitly modeling the underlying physics, they learn mappings from observed signals (current, voltage, temperature, time) to target states (SOC, SOH, RUL) using training data. As summarized by Rout et al. [134], classical ML approaches (e.g., support vector regression, random forests, gradient boosting and shallow neural networks) have demonstrated competitive performance for SOH estimation when coupled with carefully engineered features.
DL methods further extend this paradigm by learning hierarchical representations directly from raw or minimally processed time-series data. For SOH and RUL estimation, architectures such as long short-term memory (LSTM) networks, gated recurrent units (GRUs), CNNs, TCNs and hybrid models with attention have been proposed [133,135,136,137]. For SOC, Liu et al. [121] and Wang et al. [138] reviewed and developed DL models that can handle complex current profiles and non-linear voltage behavior.
Probabilistic ML represents a third evolution: instead of focusing solely on point predictions, probabilistic models aim to describe full predictive distributions. Thelen et al. [119] discussed Bayesian neural networks, Gaussian processes, probabilistic graphical models and deep ensembles as tools for uncertainty quantification (UQ) in battery health prognostics. However, despite the conceptual appeal, practical integration of probabilistic ML with advanced DL architectures (e.g., GNNs, attention-based models) in battery applications remains limited in current literature.
3.3. Machine and Deep Learning for SOH and Capacity Estimation
3.3.1. Classical Data-Driven Approaches for SOH
Figure 7 is a schematic on data-driven algorithms used to map the features of batteries commonly reported in the literature. Ulrike Krewer [125] and Rout et al. [134] provided a detailed comparison of several advanced data-driven techniques for SOH estimation, including support vector regression (SVR), random forests (RF), gradient boosting and traditional artificial neural networks (ANNs). These methods typically take as input a set of hand-crafted features derived from: (1) Capacity measurements across cycles; (2) Internal resistance or pseudo-impedance features; (3) Voltage–capacity curve descriptors (e.g., dV/dQ peaks, curve segments); (4) Statistical features of current and voltage profiles.
Figure 7.
Popular data-driven algorithms, battery characteristics, and features for state-of-charge (SOC) estimation and state-of-health (SOH) prediction. Black-box approaches are completely based on data and no physically motivated model structure is assumed, while gray-box approaches are based on fusing a physically motivated model as well as data-driven techniques. The abbreviated terms for the techniques are support vector machine (SVM), Gaussian process regression (GPR), least squares (LS), neural network (NN), genetic algorithm (GA), recursive least square (RLS), Kalman filter (KL), unscented Kalman filter (UKF), extended Kalman filter (EKF), and singular value decomposition (SVD) [125].
Their review underscored that careful feature engineering and data pre-processing are crucial to achieving robust performance. For moderate-sized datasets and relatively constrained operating conditions, classical ML methods can deliver satisfactory SOH estimation accuracy with relatively low computational cost, making them practical for certain BMS implementations.
However, as usage scenarios and data volumes grow more complex, classical methods face challenges in capturing high-dimensional, nonlinear relationships and long-range temporal dependencies. This has motivated the shift toward DL-based approaches.
3.3.2. Deep Learning Architectures: RNNs, CNNs, Attention and TCNs
Shen et al. [137] proposed a DL-based method for online capacity estimation of lithium-ion batteries. Using current, voltage and temperature signals from normal operation as inputs, their model learns an end-to-end mapping to capacity, eliminating the need for periodic full-cycle diagnostic tests. The network architecture relies on deep layers to extract relevant temporal features and has demonstrated superior performance compared with traditional models on the evaluated datasets.
Zhao et al. [136] further advanced the field by presenting an AT-CNN-BiLSTM architecture for joint SOH estimation and RUL prediction. The model integrates: (1) A CNN module for local feature extraction from time-series data; (2) A bidirectional LSTM module to capture long-term dependencies and bidirectional temporal context; (3) An attention mechanism to focus on time segments that are most informative for SOH and RUL.
Their results show that this hybrid model outperforms both pure RNN and pure CNN baselines, particularly under complex cycling conditions. The attention mechanism, in particular, offers a window into which portions of the degradation trajectory are deemed most critical by the model, providing a step toward interpretability.
In another direction, the MHATTCN network proposed in [133] combines multi-health-indicator inputs with a TCN backbone and multi-head attention. Compared with traditional RNNs, TCNs offer: (1) Improved parallelization due to convolutional operations; (2) Flexible receptive fields to capture long-term temporal dependencies; (3) Stable gradients thanks to residual connections and causal convolutions.
Multi-head attention is leveraged to assign different weights to different indicators and time segments, effectively learning a dynamic importance weighting. Experimental results in ref. [133] indicate that MHATTCN achieves higher accuracy and training efficiency than conventional LSTM-based models, demonstrating the promise of TCN + attention architectures for health state estimation.
The importance of data preparation for DL-based models was emphasized by the study on LSTM modeling for mild-hybrid vehicle applications [135]. The authors systematically investigated: (1) Sampling rates and window sizes for time-series segmentation; (2) Normalization strategies and feature scaling; (3) Train/validation/test splits that avoid “temporal leakage”; (4) Effects of dataset imbalance across aging stages.
Their findings make clear that methodologically sound data preparation can be as important as the choice of network architecture, and that improper splitting or feature processing can yield overly optimistic yet misleading performance estimates.
3.3.3. Graph Neural Networks and Multi-Expert Fusion for SOH
Accurate estimation of the State of Health (SOH) is pivotal for the safe and efficient operation of lithium-ion batteries throughout their lifecycle [125]. Traditional approaches often struggle in scenarios involving complex operating conditions and limited data, primarily due to parameter mismatch and poor generalization. Modeling battery charge–discharge cycles as temporal graphs offers a promising solution to these challenges [125].
To move beyond treating time-series as simple vectors, several recent works have explored the use of graph neural networks.
Pan et al. [128] developed a correlation based-graph neural network (GNN) estimation framework as illustrated in Figure 8. Two correlation analysis methods, Pearson’s correlation coefficient and the Mantel test, were applied to extract valid information and identify critical health features. Regression modeling was then used to estimate the current state of health (SOH) of a battery. The SHAP (Shapley Additive exPlanations) values derived from the interpretability analysis were utilized to select the most important health features from the regression model. Batteries from two datasets with various working conditions are chosen to validate the framework’s effectiveness. Experimental results show that the framework, designed for practical applications, demonstrates exceptional capability in accurately and rapidly estimating battery health conditions [128].
Figure 8.
Health prognosis framework real-word data from an energy storage station (used as a practical case) and raw battery data from SNL [128].
In the study of Ref. [139], partial discharge curves are discretized into nodes, with edges connecting adjacent points or segments with similar characteristics. A graph convolution network (GCN) as depicted in Figure 9 then processes this graph representation to produce SOH estimates. This approach has two salient advantages: (1) It relaxes the requirement for full charge/discharge cycles, aligning better with real-world usage where only partial cycles are often observed. (2) It explicitly models the relationships between local segments of the curve, enabling the network to capture both local and global pattern information.
Figure 9.
GCN Estimation Model, the proposed GCN SOH estimation model is designed to capture the inter-cycle spatial information and provide insights into the overall degradation pattern of the battery utilized by GCN [139].
Kim and Chung [130] extended the GNN paradigm by introducing an adaptive loss-based framework for SOH prediction. Recognizing that different degradation stages (e.g., early, middle, late aging) contribute differently to the final objective, they designed a loss function that adaptively reweights samples or cycles based on their importance or difficulty. Combined with a GNN that captures structural relationships in the data, this approach improved robustness against outliers and enhanced performance in late-life prediction, where uncertainty is typically larger.
In essence, a battery system can be viewed as a dynamic heterogeneous network composed of battery cells, sensors, and environmental factors. Physical connections between cells give rise to thermal conduction and electrical coupling (edges), while charge–discharge cycles form temporal edges. Node attributes include key measurements such as voltage and temperature. This spatiotemporal coupling aligns naturally with graph-structured data, making GRL a promising approach to address challenges in battery management.
Yao et al. [127] proposed a novel CL-GraphSAGE framework that leverages graph neural networks (GNN) to integrate both temporal and spatial features of health indicators (HIs) for accurate prediction of battery state of health (SOH). First, highly correlated HIs are selected by calculating Pearson correlation coefficients between various HIs and SOH to construct the graph structure; second, convolutional neural networks (CNN) and long short-term memory neural networks (LSTM) are utilized to extract temporal features of HIs, respectively; finally, the graph sampling and aggregating (GraphSAGE) method is employed to perform message passing on the predefined graph structure, mining deep-level associative information between HIs. Figure 10 shows the proposed CL-GRAPHSAGE for battery SOH prediction framework. The CL-GRAPHSAGE includes CNN, LSTM and GRAPHSAGE. The extracted health indicators (his) from charging and discharging processes are used to build a graph structure. Then the HI’s temporal features are extracted by CNN and LSTM, and the spatial features are obtained by GRAPHSAGE. Finally, the SOH is ac- quired by multilayer perceptron (MLP). Figure 11 shows the aggregation process of GraphSAGE for the given graph [127]. Figure 11b displays the corresponding topological and node features by the given graph structure in Figure 11. Taking the red Node A in Figure 11a as an example, GraphSAGE updates the information of the node A by fusing the neighborhoods’ information [127].
Figure 10.
CL-GRAPHSAGE framework for battery SOH prediction Based on Multiple Health Indicators [127].
Figure 11.
Aggregation process of GRAPHSAGE: (a) the given graph; (b) aggregated embedding [127].
This work validated the effectiveness of the proposed method on MIT, NASA public datasets and experimental datasets, and compares it with CNN, LSTM, graph convolutional networks (GCN) and graph attention networks (GAT). Results show that the proposed CL-GraphSAGE method achieves a root mean square error as low as 0.2%, and test results on different datasets collectively verify the feasibility of this method [127].
Another representative method explored the potential utility of aging information, gathered from routine operational data beyond the standard input collection region, as proxy labels (PLS) to establish nonlinear mappings between a short charging segment and SOH. To achieve this, Tao et al. [140] developed a multitask learning (MTL) framework that combines self-supervised learning, adversarial learning, and domain adaptation techniques to fully utilize labeled and unlabeled data, enhancing the model’s generalization capability for battery health monitoring. The framework consists of two parts: a deep MTL model for estimating pls from short charging segments, and a lightweight multivariate Gaussian Process Regression (GPR) model for mapping pls to SOH. This method was validated on battery datasets under various chemical systems and cycling temperatures, and achieved a mean absolute error (MAE) of less than 1.3% in all cases, significantly outperforming baseline methods [121].
Beyond GNNs, Fan et al. [141] proposed a multi-expert fusion (MEF) framework for SOH estimation. In their approach, several expert models are trained, each focusing on specific features, aging stages or operating regimes. A fusion module (e.g., attention or gating) combines expert outputs with dynamically determined weights for each input.
This design not only improves predictive accuracy by leveraging complementary strengths of different experts, but also provides a degree of interpretability: the expert weights can be analyzed to infer which degradation modes or indicators are dominant for a given cell and condition. The MEF paradigm resonates with ideas in multi-task and mixture-of-experts learning and suggests a path toward more interpretable and modular health estimation systems.
To address the issue of data scarcity in few-shot scenarios, the integration of meta-learning and graph representation learning has emerged as a promising direction. A domain-similarity-based meta-learning approach for lithium-ion battery SOH estimation under limited data conditions achieves significant improvements through a multi-module collaborative framework. Specifically, the dynamic-static feature extraction module separates long-term degradation trends from short-term fluctuations in battery data. The task ranking module applies the maximum mean discrepancy (MMD) algorithm to quantify inter-task similarity under varying operating conditions, prioritizing tasks with smaller domain gaps to significantly reduce retraining overhead. The LSTM-based meta-learning module learns a generalizable feature mapping across multiple few-shot tasks, enabling rapid adaptation to new battery chemistries or usage patterns with minimal data.
In the realm of non-graph-based SOH estimation under few-shot settings, various effective techniques have also emerged. One representative method employs feature mode decomposition and transfer learning: it utilizes an improved complete ensemble empirical mode decomposition with adaptive noise (CEEMDAN) [142] to decompose complex battery signals into intrinsic mode functions, from which features highly correlated with battery health are selected. These features are then input into a hybrid prediction model composed of LSTM and backpropagation (BP) networks. Transfer learning is employed to reuse feature extraction capabilities learned from other battery datasets, thereby enhancing prediction performance on scarce target data.
The SOH of the battery at different cycles along the whole aging process constitutes time-series data, and the SOH at a given cycle is closely related to the previous cycles. For this type of data, recurrent neural network (RNN) has natural advantages [123]. By memorizing the historical information of battery, it can improve the predictions accuracy of future. As an improved RNN, LSTM can avoid the gradient vanishing or explosion in the training process of RNN [123]. The schematic of a basic LSTM cell is presented in Figure 12. LSTM excels at modeling temporal sequences, making it well-suited for capturing the dynamic degradation patterns of batteries [121,122,123,126,128,140,143,144,145,146,147,148]. On the other hand, XGBOOST optimizes feature combinations through gradient boosting [126,146]. A hybrid SOH estimation approach that integrates LSTM with XGBOOST leverages the strengths of both models: it performs multidimensional feature analysis by jointly considering voltage, internal resistance, charge/discharge capacity, and other key indicators. Under limited data conditions, this method achieves a root mean square error (RMSE) of only 3.8% for SOH estimation, demonstrating strong robustness and predictive accuracy. Collectively, these methods provide diverse solutions for SOH estimation in few-shot battery scenarios. With the continued integration of graph representation learning, meta-learning, and advanced signal processing techniques, the intelligence and precision of battery health management are expected to improve significantly in the future.
Figure 12.
The Architecture of LSTM [121,135,149].
3.3.4. Federated Learning for SOH
The research team led by Xuan Zhang at Tsinghua University proposed a federated learning–based collaborative classification framework for retired batteries [150]. By aggregating multiple local random forest models through a Wasserstein-distance voting mechanism, the framework enables cathode material classification with an accuracy exceeding 95% using only a single charge–discharge cycle. A privacy budget (PB) mechanism is incorporated to ensure data security. However, the model relies solely on random forests, which lack the capacity to capture the complex structural features of advanced material systems. To address this limitation, the integration of GNNs is necessary for modeling atom-level material characteristics. In a separate effort, the research team at Macau Polytechnic University [151] targeted electric vehicle applications by optimizing client selection strategies to improve federated training efficiency. They adopted knowledge distillation to compress a server-side pretrained GNN into a lightweight client-side network. The model adopts an LSTM-based seq2seq structure, combining historical degradation data with future operational condition features to achieve one-shot prediction of battery degradation trajectories. Figure 13 illustrates the overall idea of the model structure. This approach achieved state-of-the-art SOH prediction accuracy (error < 3%) in a decentralized training setting while mitigating data leakage risks. By combining dynamic client selection and model compression, the framework strikes a balance between communication efficiency and predictive accuracy.
Figure 13.
Model structure of the predictive model with the LSTM-based encoder–decoder structure [151].
3.3.5. Transfer Learning for Batteries
In transfer learning for batteries, parameter transfer and structural transfer achieve effective cross-domain knowledge transfer through pretraining and topological prior reuse, respectively. However, in practical applications, data scarcity and battery heterogeneity remain major challenges in second-life scenarios, and traditional methods often struggle to cope with these complex issues. Therefore, based on the core ideas of the aforementioned transfer learning, Tao et al. from Tsinghua University further proposed a deep generative transfer learning framework to address the problems of data deficiency and cross-domain differences in the estimation of the remaining capacity (RRC) of retired lithium-ion batteries [152]. Figure 14 [152] shows a detailed workflow. The proposed approach is promising in terms of saving intensive data curation time and showing flexibility in updating trained models to new domains without retraining from scratch. The proposed unified data generation and knowledge transfer paradigm is promising for many other energy predictive tasks by preferentially generalizing non out-of-distribution (OOD) data and then adapting to OOD conditions under the guidance of available field data [152]. Based on 20,160 samples under 10 SOC conditions, they generated voltage response dynamic data under multi-SOC conditions, with statistical results showing high similarity and confidence. The model requires only minimal field data (merely 2% of the complete sample size) to achieve RRC estimation: for two types of second-life batteries with significantly different aging behaviors, the mean absolute percentage errors are as low as 7.2% and 3.6%, respectively [152]. While retaining established knowledge in existing domains, the model significantly reduces RRC estimation risks caused by field data scarcity in new domains; at the 95% confidence level, the maximum RRC estimation risk reduction reaches 49% [152]. This unified paradigm combining data generation and transfer learning outperforms current state-of-the-art machine learning methods and equivalent circuit model methods across various data availability conditions [152]. The “generation-transfer” paradigm, by prioritizing generalization of in-distribution data and then adapting to out-of-distribution conditions under limited field data guidance, provides numerous potential application insights for other predictive maintenance tasks.
Figure 14.
The experimental flow of the deep generative transfer learning for immediate state-of-health estimation of heterogeneous second-life lithium-ion batteries [152].
3.4. Machine and Deep Learning for SOC Estimation
3.4.1. Deep Learning Architectures for SOC
SOC estimation is a foundational task in BMS, directly related to energy management and user-facing indicators such as state-of-charge displays and range estimates. Liu et al. [121] summarized the landscape of DL-based SOC estimation, covering architectures such as: LSTM and GRU networks for sequential data modeling; CNNs for local pattern extraction from current and voltage time-series; Hybrid CNN–RNN architectures; Emerging attention-based and Transformer-like models.
Their review concluded that DL methods often significantly outperform traditional techniques (e.g., Coulomb counting, open-circuit voltage-based methods, simple ECM + Kalman filtering) in complex and dynamic load profiles, due to their ability to capture nonlinear relationships and temporal dependencies. However, they noted several practical challenges: (1) High data demands for training and validation; (2) Large model sizes and computational requirements that may exceed typical BMS hardware capabilities; (3) Risks of poor generalization when test conditions differ from those seen during training.
These observations point to the need for lighter-weight yet robust DL models, as well as strategies for cross-condition generalization and domain adaptation.
3.4.2. Transfer Learning and SOC Estimation with Small Target Sets
Wang et al. [138] addressed the challenge of small target sample sets in SOC estimation, a common scenario when deploying a model to a new cell type or application with limited labeled data. They proposed an improved GRU-based SOC estimator with transfer learning: (1) A base GRU model is trained on a source dataset with rich SOC labels under various operating conditions. (2) For a target domain with very few labeled samples, the pre-trained model is fine-tuned using a small number of target-specific data points. (3) Network modifications and training strategies were designed to adapt to the small-target regime while mitigating overfitting.
Experimental results demonstrated that the transfer learning approach significantly outperforms models trained from scratch on the limited target data, and remains robust across different load profiles. These works provide concrete evidence that transfer learning is a viable solution to the widespread “data scarcity in new domains” problem for SOC estimation.
Xiaopeng Tang et al. [153] proposed a meta-learning-based lifetime classification method that trains a convolutional neural network (CNN) using data from the first three cycles, constructs an adjacency matrix by determining whether the lifetimes of two batteries are similar, and achieves clustering and grouping of retired batteries; experiments on 38 batteries show that compared to the traditional capacity-resistance method, this method reduces lifetime loss by at least 20%, validating the potential of supervised learning in battery classification. Another work [154] by Xiaopeng Tang proposed a lifetime abnormality detection method for batteries based on few-shot learning and using only the first-cycle aging data. They built a supervised few-shot learning neural network model as given in Figure 15, where the training objective is to determine whether any two batteries belong to the same category (normal or abnormal), rather than directly classifying individual batteries. Verified with the largest known dataset with 215 commercial lithium-ion batteries, the method can identify all abnormal batteries, with a false alarm rate of only 3.8% [154]. It is also found that any capacity and resistance-based approach can easily fail to screen out a large proportion of the abnormal batteries, which should be given enough attention. This work highlights the opportunities to diagnose lifetime abnormalities via “big data” analysis, without requiring additional experimental effort or battery sensors, thereby leading to extended battery life, increased cost–benefit, and improved environmental friendliness [154].
Figure 15.
The battery lifetime abnormality detection method, a supervised data-driven algorithm based on few-shot learning, and it basically had two steps—training and testing [154].
3.4.3. SOC Estimation Under Different Load Profiles Using ML
Harinarayanan and Balamurugan [131] studied SOC estimation for a lithium-ion pouch cell using several ML algorithms under different load profiles. By comparing methods such as SVR, tree-based models and shallow neural networks with conventional techniques, they found that ML models generally deliver improved SOC accuracy under complex, dynamic current profiles, particularly when trained on adequately diverse data, and the performance of ML models degrades when test load profiles extend beyond the distribution of training data, highlighting the importance of representative training sets.
Their results align with the conclusions of Liu et al. [121] and underscore an important point: data coverage is a critical determinant of ML/DL performance, often more so than the choice of model architecture.
3.4.4. Common Feature Extraction and Transfer Learning for SOC Estimation
Addressing the issue of simplified state of charge (SOC) estimation strategies in vehicle battery management systems (V-BMS) due to limited computational resources, a SOC estimation method suitable for cloud battery management systems (C-BMS) is proposed [149]; Figure 16 shows the laboratory battery SOC estimation model. The experimental data are processed by the common feature extraction method [149]. A common feature extraction method combining empirical mode decomposition (EMD) and compensation strategies is proposed to improve model generalization capability, and a long short-term memory (LSTM) neural network is employed to construct the basic SOC estimation model [149]; Parameter-based transfer learning and adaptive weighting strategies are introduced to achieve model transfer from laboratory data to actual vehicle data and battery pack SOC estimation [149]; The effectiveness of this method is validated on laboratory datasets and cloud platform datasets, with a maximum root mean square error (RMSE) of 2.2% for individual battery cell SOC estimation and a maximum RMSE of 1.3% for battery pack SOC estimation [149].
Figure 16.
Battery SOC Estimation Model [149].
3.5. Key Technical Pathways for Few-Shot Scenarios
Traditional model-driven or large-sample data-driven methods often rely on long-term accelerated aging tests and high-quality full-lifetime data, which are difficult to satisfy in new chemical systems (such as sodium-ion batteries), new operating conditions, and large-scale engineering applications. To address the problems of lifetime trajectory prediction, SOH/SOH anomaly identification, and RUL prediction under the constraints of “small samples, high uncertainty, and multiple scenarios,” battery health modeling work around few-shot learning has developed rapidly in recent years. Few-shot [126,129,144,146,147,148,154,155,156] battery scenarios are primarily challenged by two factors: data sparsity, such as limited early-cycle data for new battery types, and dynamic heterogeneity [126,144], where thermal-electrical coupling relationships between cells vary with operating conditions.
3.5.1. Few-Shot Battery Lifetime and Trajectory Prediction
Meng et al. proposed a multi-scenario transferable learning framework for early prediction of lithium-ion battery lifespan trajectories with few-shot data [155]. The key idea is to generate abundant pseudo trajectories from the full lifespan curve of a single cell and then transfer the learned model to other cells and scenarios. By expanding the polynomial coefficients within a limited range, 50 synthetic degradation trajectories are generated to mimic realistic variations in degradation patterns. A hybrid deep model combining a gated recurrent unit (GRU) and one-dimensional convolutional neural network (1D CNN) is pretrained on the pseudo trajectories [155]. In the target domain, only the first 100 cycles of a cell are used to fine-tune part of the network, while other layers are frozen. The approach is validated on the MIT A123 dataset and a laboratory NMC dataset, achieving average RMSE and MAE typically below 1% SOH across batches and scenarios [155].
This study demonstrates that synthetic trajectory generation, when combined with transfer learning, can greatly reduce the need for fully cycled cells while maintaining multi-scenario trajectory prediction accuracy.
3.5.2. Lifetime Prediction and Abnormality Detection from Very Few Cycles
Sui et al. [156] tackled the problem of full-lifespan prediction from only six early charging cycles. They constructed 5 × 5 grayscale images from the differences between the 100th–104th cycles and the 10th cycle, and trained an autoencoder-based prototypical network for few-shot lifetime prediction on 124 A123 LFP/graphite cells: Batteries are first classified into short-life (<800 cycles) and long-life (>800 cycles) groups via few-shot classification. Separate Gaussian process regression models are then trained within each group using the learned prototypes, achieving mean absolute percentage error (MAPE) around 8–9% while using only six charging cycles as input.
Tang et al. further pushed the limit to the first cycle by proposing a few-shot abnormality detection method based solely on first-cycle aging data [154]. A metric-learning-based few-shot network is trained to determine whether two cells belong to the same lifetime class. On a dataset of 215 commercial NCA/graphite cells: Cells with significantly higher local aging rates in the last 25% of life are labeled as “abnormal”. Using only first-cycle constant-current charging data, the method identifies all abnormal cells (true positive rate 100%) with a false alarm rate of only 3.8% and an F2-score of 89.74% [154].
These works collectively show that, with carefully designed features and latent spaces, useful lifetime information can indeed be extracted from as little as 1–6 cycles.
3.5.3. Semi-Supervised and Self-Supervised Few-Shot Prediction and SOH Estimation
Guo et al. proposed a semi-supervised learning framework termed Partial Bayesian Co-Training (PBCT) for explainable few-shot lifetime prediction [126]. The framework uses both labeled and unlabeled early-cycle features (e.g., voltage–capacity differences, charging time, initial resistance) to train [126]. A complete-view linear regression model that uses all 20 early-cycle features. A partial-view linear regression model that uses only a subset of physically important features (such as energy dissipation, initial internal resistance and early-stage charging time). Under a Bayesian graphical model, the partial-view model generates pseudo labels for unlabeled cells, which guide the learning of the complete-view model via co-training. On three sub-datasets of the MIT–Stanford battery dataset, PBCT: (1) Outperforms Lasso, Elastic Net and a VAE-based data augmentation baseline by 9.8–21.9% in RMSE. (2) Reduces the total cycle cost (number of aging cycles required for labeled data) by up to 26.9%, translating directly into economic savings [126]. (3) Enhances interpretability by consistently identifying energy dissipation features, initial resistance, and early charging time as key predictors across repeated experiments.
This work highlights that unlabeled data, when properly exploited, can significantly improve both accuracy and physical interpretability in few-shot lifetime modeling.
Shen et al. introduced a semi-supervised SOH estimation method based on Masked Autoencoders (MAEs). Large-scale unlabeled field charging data from EVs are used to pretrain a Vision Transformer-based MAE [146]. Time-series signals including current, average cell voltage, maximum/minimum cell voltage, maximum/minimum cell temperature, SOC and timestamp are partitioned into fixed-length patches. Randomly masking 75% of the patches, the MAE reconstructs the missing ones, achieving low weighted MSE and absolute relative error (<0.6%), indicating robust latent representation learning. The pretrained encoder is then fine-tuned with only 20% of labeled data. On a fixed test set, the method achieves RMSE of 2.16% and R2 of 0.69. When focusing on 3.8–3.9 V voltage segments (which correspond to secondary peaks in incremental capacity curves), RMSE improves to 1.84% [146].
Moreover, even using only charge quantity and average voltage over short segments (~21.33 min of charging), the method maintains RMSE around 1.9%. This work illustrates that self-supervised pretraining on unlabeled field data, followed by few-shot fine-tuning, can effectively bridge the gap between laboratory models and real-world EV data [146,157].
3.5.4. Bayesian Deep Networks with Degradation Pattern and GAF Features
Zhang et al. developed a Bayesian deep neural network (BDNN) framework for SOH estimation under few-shot learning [144]. From the perspective of feature extraction, they proposed (1) The degradation pattern (DP), a temporal-spatial matrix constructed from discharge profiles, capturing the evolution of capacity at different voltages. (2) The Gramian angular field (GAF), a 2D image encoding the capacity trajectory, which enriches temporal dependency and distribution information.
A dual-channel BDNN, composed of Bayesian CNN, Bayesian LSTM and Bayesian fully connected layers [158], is trained via variational inference to output both SOH estimates and predictive uncertainty (aleatoric and epistemic). Across MIT–Stanford, CALCE and Oxford datasets: (i) With only 1–10% of data used for training, BDNN achieves MAE and RMSE often below 1–2% SOH and clearly outperforms CNN–LSTM, attention BiLSTM, variational LSTM, TCN and EMD + LSTM + GPR baselines. (ii) In multi-step-ahead prediction (up to 50 steps), BDNN retains superior accuracy and robustness, especially at longer horizons [144].
This framework demonstrates that multi-dimensional features and Bayesian modeling enable highly accurate and uncertainty-aware SOH estimation from limited training data.
3.5.5. Meta-Learning for Multi-Domain SOH and RUL
Yang et al. proposed BayesMRG (Bayesian Meta Random Graph Implicit Enhanced Network) for RUL prediction under few-shot and uncertainty interference scenarios [129]. The model Employed a bilevel optimization framework to learn meta-parameters across multiple source tasks (different cells, conditions). It utilized random feature functions and graph neural networks to model pairwise dependencies between feature representations, forming random graph features via multi-layer message passing and aggregation. Furthermore, the model incorporated dual causal variable semantics to capture causal relationships between degradation tasks and random graph features, and uses variational inference to approximate the posterior distributions of model parameters and latent variables.
On NASA and CALCE datasets, BayesMRG achieves more than 40% improvement in RMSE/MAE compared with strong baselines (e.g., CNN–LSTM–DNN, TCN–GRU–DNN), while also providing explicit uncertainty quantification [129].
Zhao et al. focused on multi-domain few-shot SOH estimation using relaxation voltages [159]. A parallel CNN–Attention architecture extracts transferable health features from relaxation voltage curves at different temperatures and for different chemistries (NCA/NCM). An improved MAML-based meta-learning strategy is employed. It first pre-trains a meta-model on multi-domain source data (involving one chemical system at various temperatures) and then adapts it to target temperatures using only ten relaxation curves per domain.
The proposed method achieves average RMSE/MAE of 2.28%/1.79% for NCA and 1.35%/1.11% for NCM in cross-domain scenarios [159], outperforming pure fine-tuning and non-pretrained baselines.
3.5.6. Physics-Informed and Lightweight Few-Shot Models for Deployment
Yin et al. emphasized the practical need for models that are not only accurate in few-shot settings but also efficient enough for deployment on edge devices [147]. They proposed PLT-GRU, a physics-informed lightweight Transformer–GRU algorithm for few-shot SOH estimation and RUL prediction [147]. Its main features are: (1) A single-layer Transformer–GRU backbone to reduce the number of attention and recurrent layers, thereby lowering time and space complexity. (2) A physics constraint layer that softly couples capacity and internal resistance via four branches (capacity, resistance, interaction and polynomial) and learns their optimal fusion with the GRU output. (3) A meta-learning inspired adaptation strategy that allows the model to quickly adjust to new tasks with limited data.
On CALCE CS2/CX2 and NASA datasets, PLT-GRU reduces parameters by 94.93% and inference time from 23.4 ms to 3.11 ms per forward pass compared with a heavy T-LSTM, while maintaining RMSE around 0.05 Ah and satisfying typical engineering accuracy requirements [147,157]. This work provides an effective template for combining lightweight architectures, physics-informed constraints and few-shot learning for real-time battery management.
3.5.7. Summary
The reviewed works collectively demonstrate that battery management in few-shot scenarios is not only feasible but can achieve accuracy comparable to, or even surpassing, many large-data baselines when appropriate learning paradigms are employed. Key observations are:
Dramatic reduction in labeled data requirements: Through pseudo-trajectory generation, semi-supervised co-training, meta-learning, self-supervised pretraining and transfer learning, models can operate with as little as 1–10 early cycles, a handful of labeled cells, or even only first-cycle data for specific tasks.
Competitive accuracy and robustness: Many methods maintain RMSE/MAE below 1–2% SOH or around 5–10% lifetime error under 1–10% training data. In long-horizon and multi-scenario prediction, few-shot/meta-learning frameworks often outperform conventional deep networks trained with more data.
Improved interpretability and uncertainty quantification: PBCT, BDNN, BayesMRG and PLT-GRU provide feature importance, causal structure or predictive covariance, enabling more transparent and risk-aware decision-making.
Cross-domain and cross-chemistry transfer: Successful transfers from MIT to CALCE/NASA, from NCA to NCM, and from sodium-ion to lithium-ion batteries show that carefully designed features, normalization and few-shot adaptation mechanisms can bridge domain gaps.
Despite these advances, several gaps remain. Most studies are still cell-level and laboratory-based; few address pack-level management with cell-to-cell inconsistency, low sampling rates and strong noise. Cross-mechanism and new chemistries (e.g., solid-state, high-silicon anodes) are only starting to be explored. The systematic integration of predictive uncertainty into BMS control and safety strategies has not been fully established. Benchmarking across methods is also hindered by heterogeneous datasets, task definitions and evaluation protocols.
Future research should therefore focus on: (i) pack-level few-shot/meta-learning under real-world duty cycles; (ii) physics–data co-design for cross-mechanism, cross-chemistry transfer; (iii) unified benchmarks for few-shot battery health prediction; and (iv) closed-loop integration of uncertainty-aware predictors into battery management and safety control. With these developments, few-shot methods are expected to become a core component of next-generation intelligent battery management systems.
Table 2 provides a comparative summary of the state-of-the-art approaches across different battery management tasks, including SOC estimation, SOH/capacity estimation, RUL and lifetime prediction.
Table 2.
Comparative summary of graph-centric few-shot approaches for battery energy systems across key tasks.
4. Conclusions
This review systematically investigates the application of graph representation learning in few-shot battery scenarios, elucidating its core value and key challenges. Due to the spatiotemporal coupling characteristics of battery systems (e.g., dynamic heat conduction among cells and charge/discharge fluctuations) and the scarcity of available data (e.g., limited early-stage data for novel materials and fragmented information from retired batteries), traditional modeling approaches often fall short. Graph representation learning provides a promising breakthrough by abstracting batteries as dynamic heterogeneous graphs, where nodes encode cell attributes and edges represent coupling relationships.
This review also has synthesized recent advances in ML and DL methods for lithium-ion battery state estimation. We organized the discussion around tasks (SOH, SOC, RUL, capacity), methods (from classical ML to advanced DL architectures) and cross-cutting issues (data, generalization, uncertainty).
The key conclusions are:
- DL architectures such as LSTM/GRU, CNNs, TCNs with attention, and GNNs, as well as MEF frameworks, have achieved substantial performance gains for SOH and SOC estimation compared with classical methods, particularly under complex load conditions.
- Multi-indicator inputs and multi-expert fusion help capture diverse degradation modes and improve robustness across operating regimes. Transfer learning has shown promise in enabling SOC and SOH estimation in small-target domains.
- Probabilistic ML and uncertainty quantification remain underutilized in concrete DL models for state estimation, despite their importance for safety-critical decisions.
- Major challenges remain in terms of label scarcity, cross-domain generalization, physics–data integration and BMS-oriented deployment constraints.
- Future directions include probabilistic DL for risk-aware BMS, unified transfer/meta-learning frameworks for multi-chemistry generalization, systematic use of proxy labels and unlabeled data, and physics-informed and interpretable models.
4.1. Methodological Issues: Data, Generalization and Uncertainty
4.1.1. Data Preparation and Experimental Protocols
The methodology for data preparation and training when modeling LIBs with LSTM networks for mild-hybrid vehicle applications. Key guidelines include:
- (1)
- Selecting appropriate sampling rates to balance temporal resolution and data volume;
- (2)
- Defining window lengths for sequence segmentation that capture relevant dynamics without excessive redundancy;
- (3)
- Applying normalization and feature scaling to stabilize training;
- (4)
- Ensuring that train/validation/test splits are performed along the time axis or cell index to avoid information leakage.
They showed that violating these principles—for example, mixing data from the same cycles across training and test sets—can produce overly optimistic error metrics that do not reflect real-world performance. This methodological contribution is highly relevant to almost all subsequent DL-based studies and should be considered a baseline standard for rigorous evaluation.
4.1.2. Generalization Across Cells, Conditions and Chemistries
Despite encouraging results on specific datasets, many ML/DL models for SOH and SOC estimation have limited demonstrated ability to generalize across:
- (1)
- Different cell designs, capacities and chemistries;
- (2)
- Different temperature ranges and C-rates;
- (3)
- Different usage patterns (e.g., urban vs. Highway driving, stationary vs. Mobile applications).
Transfer learning provides initial evidence that knowledge can be transferred across domains with limited target data. GNN-based models and MEF frameworks can also be interpreted as steps toward more universal representations that capture structural similarities and heterogeneous degradation patterns.
However, systematic studies on multi-dataset, multi-chemistry generalization are rare in the current literature. This is a major barrier to practical deployment, calling for more comprehensive benchmarks and standardized evaluation protocols.
4.1.3. Probabilistic Machine Learning and Uncertainty Quantification
Robust battery diagnostics and prognostics must explicitly account for uncertainty. They reviewed probabilistic ML techniques such as:
- (1)
- Gaussian process regression;
- (2)
- Bayesian neural networks;
- (3)
- Probabilistic graphical models;
- (4)
- Monte Carlo dropout and deep ensembles.
These methods can provide predictive distributions rather than point estimates, enabling:
- (1)
- Confidence intervals for SOH, SOC and RUL predictions;
- (2)
- Risk-aware decision-making in BMS (e.g., conservative power limits when uncertainty is high);
- (3)
- More meaningful comparisons between models in terms of both accuracy and reliability.
Despite this conceptual foundation, most of the specific works considered in this review still use deterministic DL models and evaluate them solely with point-wise error metrics (RMSE, MAE, MAPE, etc.). The integration of UQ with advanced architectures like MHATTCN, AT-CNN-BiLSTM, GNNs and MEF remains largely unexplored. This represents a significant research opportunity at the intersection of probabilistic ML and advanced DL architectures for battery state estimation.
4.2. Research Gaps and Future Directions
4.2.1. Dealing with Label Scarcity and Proxy Targets
In practical applications, high-quality labels for SOH, RUL and even SOC are scarce. RUL labels require knowledge of future trajectories; SOH labels typically rely on controlled diagnostic tests that are seldom available in real-world operations. In contrast, proxy signals such as mileage, energy throughput, temperature history or simplified capacity tests may be easier to obtain.
While some works have started to exploit multiple health indicators, multi-expert fusion and transfer learning, there is still a lack of systematic frameworks that:
- (1)
- Integrate proxy labels and direct labels in a principled way (e.g., via multi-task learning);
- (2)
- Make use of unlabeled data through self-supervised or semi-supervised learning;
- (3)
- Combine few labeled samples from new cells with abundant unlabeled field data.
Future research could explore self-supervised pre-training on large volumes of unlabeled current–voltage–temperature data, followed by fine-tuning on small labeled sets for specific tasks. Multi-task and multi-modal learning frameworks could jointly predict SOC, SOH, internal resistance and other indicators, thereby leveraging shared structure across tasks and making better use of proxy information.
4.2.2. Physics–Data Fusion and Explainability
Most of the DL models discussed above are “black boxes”: they are judged by their predictive performance but provide limited insight into underlying degradation mechanisms. Although attention mechanisms and MEF provide some interpretability via learned weights, there remains a large gap between model internals and mechanistic electrochemistry.
Future directions include:
- (1)
- Physics-informed DL: Incorporating physical constraints such as mass conservation, thermodynamic limits or diffusion dynamics into network architectures or loss functions.
- (2)
- Hybrid models: Coupling reduced-order electrochemical or ECMs with DL components, where the latter learn unmodeled residuals or parameter dynamics.
- (3)
- Mechanism-aware indicators: Using curve features (e.g., dv/dq peaks) that have known relations to specific degradation modes, and analyzing how DL models weigh these features over time.
These steps can bridge the gap between purely data-driven methods and mechanistic understanding, improving both robustness and user trust.
4.2.3. Towards Deployable, Risk-Aware BMS Algorithms
For BMS deployment, models must satisfy additional constraints beyond prediction accuracy:
- (1)
- Computational efficiency and memory footprint compatible with embedded platforms;
- (2)
- Robustness to sensor noise, missing data and out-of-distribution conditions;
- (3)
- Safety considerations, particularly under high uncertainty or extreme operating conditions.
Probabilistic DL approaches could be combined with model compression and distillation techniques to achieve this balance. For example, large models could be used offline to generate pseudo-labels and uncertainty estimates, which are then distilled into smaller, deployable models that retain calibrated uncertainty information.
Furthermore, future research should prioritize evaluation under realistic deployment scenarios, e.g., long-term field data, heterogeneous cell populations and fleet-level health monitoring, rather than solely on small laboratory datasets.
Author Contributions
Investigation, writing—original draft preparation and writing—review and editing, X.Z.; writing—review and editing, supervision, project administration, funding acquisition, S.W. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by Research on the Key Technologies of Dynamically Reconfigurable Battery Modules Based on Digital Twins, project number STZX202307; and Optimization of an Independent Operation DC Microgrid Configuration Scheme and Coordinated Control Study, project number 51867020.
Data Availability Statement
The data that has been used are confidential.
Acknowledgments
All authors thank the editors and reviewers for their attention to the paper.
Conflicts of Interest
The authors declare that they have no known competing financial interests or Personal relationships.
References
- Khoshraftar, S.; An, A. A Survey on Graph Representation Learning Methods. ACM Trans. Intell. Syst. Technol. 2024, 15, 1–55. [Google Scholar] [CrossRef] [Scilit]
- Mo, Y.; Peng, L.; Xu, J.; Shi, X.; Zhu, X. Simple Unsupervised Graph Representation Learning. In Proceedings of the AAAI Conference on Artificial Intelligence, Online, 22 February–1 March 2022; Volume 36, pp. 7797–7805. [Google Scholar] [CrossRef] [Scilit]
- Ju, W.; Fang, Z.; Gu, Y.; Liu, Z.; Long, Q.; Qiao, Z.; Qin, Y.; Shen, J.; Sun, F.; Xiao, Z.; et al. A Comprehensive Survey on Deep Graph Representation Learning. Neural Netw. 2024, 173, 106207. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Zhang, D.; Yin, J.; Zhu, X.; Zhang, C. Network Representation Learning: A Survey. IEEE Trans. Big Data 2020, 6, 3–28. [Google Scholar] [CrossRef] [Scilit]
- Shen, Y.; Jiang, X.; Li, Z.; Wang, Y.; Xu, C.; Shen, H.; Cheng, X. UniSKGRep: A Unified Representation Learning Framework of Social Network and Knowledge Graph. Neural Netw. 2023, 158, 142–153. [Google Scholar] [CrossRef] [Scilit]
- Dai, D.; Chen, Y.; Carns, P.; Jenkins, J.; Zhang, W.; Ross, R. GraphMeta: A Graph-Based Engine for Managing Large-Scale HPC Rich Metadata. In Proceedings of the 2016 IEEE International Conference on Cluster Computing (CLUSTER), Taipei, Taiwan, 13–15 September 2016; IEEE: New York; NY, USA, 2016; Volume 3, pp. 298–307. [Google Scholar]
- Schafer, J.B.; Konstan, J.; Riedl, J. Recommender Systems in E-Commerce. In Proceedings of the 1st ACM Conference on Electronic Commerce, Denver, CO, USA, 3–5 November 1999; ACM: New York, NY, USA, 1999; pp. 158–166. [Google Scholar]
- Dai, R.; Liu, G.; Wang, Z.; Kan, B.; Yuan, C. A Novel Graph-Based Energy Management System. IEEE Trans. Smart Grid 2020, 11, 1845–1853. [Google Scholar] [CrossRef] [Scilit]
- Zhang, B.B.; Liu, X.; Xiao, B.; Hafsia, A.B.; Gao, K.; Xu, Y.; Zhou, J.; Chen, Y. High-Performance X-Ray Detection Based on One-Dimensional Inorganic Halide Perovskite CsPbI3. J. Phys. Chem. Lett. 2020, 11, 432–437. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Ernst, P.; Meng, C.; Siu, A.; Weikum, G. KnowLife: A Knowledge Graph for Health and Life Sciences. In Proceedings of the 2014 IEEE 30th International Conference on Data Engineering, Chicago, IL, USA, 31 March–4 April 2014; IEEE: New York; NY, USA, 2014; pp. 1254–1257. [Google Scholar]
- Ernst, P.; Siu, A.; Weikum, G. KnowLife: A Versatile Approach for Constructing a Large Knowledge Graph for Biomedical Sciences. BMC Bioinform. 2015, 16, 157. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Leskovec, J. Machine Learning with Graphs. Available online: http://cs224w.stanford.edu (accessed on 9 September 2025).
- Zhang, C.; Ding, K.; Li, J. Few-Shot Learning on Graphs. In Handbook on Neurosymbolic AI and Knowledge Graphs; Hitzler, P., Dalal, A., Mohammad Saeid Mahdavinejad, S.S.N., Eds.; IOS Press: Amsterdam, The Netherlands, 2025; pp. 96–117. ISBN 96-117. [Google Scholar]
- Wu, T.; Ma, H.; Wang, C.; Qiao, S.; Zhang, L.; Yu, S. Heterogeneous Representation Learning and Matching for Few-Shot Relation Prediction. Pattern Recognit. 2022, 131, 108830. [Google Scholar] [CrossRef] [Scilit]
- Yao, H.; Zhang, C.; Wei, Y.; Jiang, M.; Wang, S.; Huang, J.; Chawla, N.V.; Li, Z. Graph Few-Shot Learning via Knowledge Transfer. In Proceedings of the AAAI 2020—34th AAAI Conference on Artificial Intelligence 2020, New York, NY, USA, 7–12 February 2020; pp. 6656–6663. [Google Scholar] [CrossRef] [Scilit]
- Ding, K.; Wang, J.; Li, J.; Shu, K.; Liu, C.; Liu, H. Graph Prototypical Networks for Few-Shot Learning on Attributed Networks. In Proceedings of the International Conference on Information and Knowledge Management, Proceedings 2020. Galway, Ireland, 19–23 October 2020; pp. 295–304. [Google Scholar] [CrossRef] [Scilit]
- Wang, Y.; Yao, Q.; Kwok, J.T.; Ni, L.M. Generalizing from a Few Examples. ACM Comput. Surv. 2021, 53, 1–34. [Google Scholar] [CrossRef] [Scilit]
- Sung, F.; Yang, Y.; Zhang, L.; Xiang, T.; Torr, P.H.S.; Hospedales, T.M. Learning to Compare: Relation Network for Few-Shot Learning. In Proceedings of the 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition, Salt Lake City, UT, USA, 18–22 June 2018; IEEE: New York; NY, USA, 2018; pp. 1199–1208. [Google Scholar]
- Snell, J.; Swersky, K.; Zemel, R.S. Prototypical Networks for Few-Shot Learning. Adv. Neural Inf. Process. Syst. 2017, 2017, 4078–4088. [Google Scholar]
- Sun, Q.; Liu, Y.; Chua, T.-S.; Schiele, B. Meta-Transfer Learning for Few-Shot Learning. In Proceedings of the 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Long Beach, CA, USA, 16–20 June 2019; IEEE: New York, NY, USA, 2019; Volume 2019, pp. 403–412. [Google Scholar]
- Yue, Z.; Zhang, H.; Sun, Q.; Hua, X.-S. Interventional Few-Shot Learning. Adv. Neural Inf. Process. Syst. 2020, 33, 2734–2746. [Google Scholar]
- Kotia, J.; Kotwal, A.; Bharti, R.; Mangrulkar, R. Few Shot Learning for Medical Imaging. In Studies in Computational Intelligence; Springer International Publishing: New York, NY, USA, 2021; Volume 907, pp. 107–132. ISBN 9783030506414. [Google Scholar]
- Feyjie, A.R.; Azad, R.; Pedersoli, M.; Kauffman, C.; Ayed, I.B.; Dolz, J. Semi-Supervised Few-Shot Learning for Medical Image Segmentation. arXiv 2020, arXiv:2003.08462. [Google Scholar]
- Zou, Y.; Zhang, S.; Li, Y.; Li, R. Margin-Based Few-Shot Class-Incremental Learning with Class-Level Overfitting Mitigation. Adv. Neural Inf. Process. Syst. 2022, 35, 27267–27279. [Google Scholar]
- Wang, H.; Wang, J.; Zhao, Y.; Liu, Q.; Liu, M.; Shen, W. Few-Shot Learning for Fault Diagnosis With a Dual Graph Neural Network. IEEE Trans. Ind. Inform. 2023, 19, 1559–1568. [Google Scholar] [CrossRef] [Scilit]
- Wu, Z.; Pan, S.; Chen, F.; Long, G.; Zhang, C.; Yu, P.S. A Comprehensive Survey on Graph Neural Networks. IEEE Trans. Neural Netw. Learn. Syst. 2021, 32, 4–24. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Corso, G.; Stark, H.; Jegelka, S.; Jaakkola, T.; Barzilay, R. Graph Neural Networks. Nat. Rev. Methods Primers 2024, 4, 17. [Google Scholar] [CrossRef] [Scilit]
- Zhou, J.; Cui, G.; Hu, S.; Zhang, Z.; Yang, C.; Liu, Z.; Wang, L.; Li, C.; Sun, M. Graph Neural Networks: A Review of Methods and Applications. AI Open 2020, 1, 57–81. [Google Scholar] [CrossRef] [Scilit]
- Wu, L.; Cui, P.; Pei, J.; Zhao, L.; Guo, X. Graph Neural Networks: Foundation, Frontiers and Applications. In Proceedings of the 29th ACM SIGKDD Conference on Knowledge Discovery and Data Mining, Long Beach, CA, USA, 6–10 August 2023; ACM: New York, NY, USA, 2023; pp. 5831–5832. [Google Scholar]
- Liu, Z.; Zhou, J. Introduction to Graph Neural Networks; Synthesis Lectures on Artificial Intelligence and Machine Learning; Springer: Berlin/Heidelberg, Germany, 2020; Volume 14, pp. 1–127. [Google Scholar] [CrossRef] [Scilit]
- Vilalta, R.; Drissi, Y. A Perspective View and Survey of Meta-Learning. Artif. Intell. Rev. 2002, 18, 77–95. [Google Scholar] [CrossRef] [Scilit]
- Hospedales, T.M.; Antoniou, A.; Micaelli, P.; Storkey, A.J. Meta-Learning in Neural Networks: A Survey. IEEE Trans. Pattern Anal. Mach. Intell. 2021, 44, 5149–5169. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Vettoruzzo, A.; Bouguelia, M.-R.; Vanschoren, J.; Rögnvaldsson, T.; Santosh, K. Advances and Challenges in Meta-Learning: A Technical Review. IEEE Trans. Pattern Anal. Mach. Intell. 2024, 46, 4763–4779. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Spinelli, I.; Scardapane, S.; Uncini, A. A Meta-Learning Approach for Training Explainable Graph Neural Networks. IEEE Trans. Neural Netw. Learn. Syst. 2024, 35, 4647–4655. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Choudhary, N.; Rao, N.; Reddy, C.K. Hyperbolic Graph Neural Networks at Scale: A Meta Learning Approach. Adv. Neural Inf. Process. Syst. 2023, 36, 44488–44501. [Google Scholar]
- Zhou, F.; Trajcevski, G.; Cao, C.; Zhong, T.; Zhang, K.; Geng, J. Meta-GNN: On Few-Shot Node Classification in Graph Meta-Learning. In Proceedings of the International Conference on Information and Knowledge Management, Proceedings 2019. Beijing, China, 3–7 November 2019; pp. 2357–2360. [Google Scholar] [CrossRef] [Scilit]
- Finn, C.; Abbeel, P.; Levine, S. Model-Agnostic Meta-Learning for Fast Adaptation of Deep Networks. In Proceedings of the 34th International Conference on Machine Learning, ICML 2017, Sydney, Australia, 6–11 August 2017; Volume 3, pp. 1856–1868. [Google Scholar]
- Finn, C.; Xu, K.; Levine, S. Probabilistic Model-Agnostic Meta-Learning. Adv. Neural Inf. Process. Syst. 2019, 31, 9516–9527. [Google Scholar] [CrossRef] [Scilit]
- Kim, T.; Yoon, J.; Dia, O.; Kim, S.; Bengio, Y.; Ahn, S. Bayesian Model-Agnostic Meta-Learning. Adv. Neural Inf. Process. Syst. 2018, 31, 7332–7342. [Google Scholar]
- Wang, H.; Mi, J.; Guo, X.; Hu, P. Meta-Learning Adaptation Network for Few-Shot Link Prediction in Heterogeneous Social Networks. Inf. Process. Manag. 2023, 60, 103418. [Google Scholar] [CrossRef] [Scilit]
- Liu, Y.; Li, M.; Li, X.; Giunchiglia, F.; Feng, X.; Guan, R. Few-Shot Node Classification on Attributed Networks with Graph Meta-Learning. In Proceedings of the 45th International ACM SIGIR Conference on Research and Development in Information Retrieval, Madrid, Spain, 11–15 July 2022; ACM: New York, NY, USA, 2022; pp. 471–481. [Google Scholar]
- Qian, Y.; Zhang, Y.; Ye, Y.; Zhang, C. Distilling Meta Knowledge on Heterogeneous Graph for Illicit Drug Trafficker Detection on Social Media. Adv. Neural Inf. Process. Syst. 2021, 32, 26911–26923. [Google Scholar]
- Zhuang, X.; Zhang, Q.; Wu, B.; Ding, K.; Fang, Y.; Chen, H. Graph Sampling-Based Meta-Learning for Molecular Property Prediction. IJCAI Int. Jt. Conf. Artif. Intell. 2023, 2023, 4729–4737. [Google Scholar] [CrossRef] [Scilit]
- Lv, Q.; Chen, G.; Yang, Z.; Zhong, W.; Chen, C.Y.C. Meta Learning with Graph Attention Networks for Low-Data Drug Discovery. IEEE Trans. Neural Netw. Learn. Syst. 2024, 35, 11218–11230. [Google Scholar] [CrossRef] [Scilit]
- Zhu, Y.; Xu, Y.; Yu, F.; Liu, Q.; Wu, S.; Wang, L. Graph Contrastive Learning with Adaptive Augmentation. In Proceedings of the Web Conference 2021, Ljubljana, Slovenia, 19–23 April 2021; ACM: New York, NY, USA, 2021; Volume 35, pp. 2069–2080. [Google Scholar]
- You, Y.; Chen, T.; Shen, Y.; Wang, Z. Graph Contrastive Learning Automated. Proc. Mach. Learn. Res. 2021, 139, 12121–12132. [Google Scholar]
- Zhu, Y.; Xu, Y.; Liu, Q.; Wu, S. An Empirical Study of Graph Contrastive Learning. arXiv 2021, arXiv:2109.01116. [Google Scholar] [CrossRef] [Scilit]
- Xu, D.; Cheng, W.; Luo, D.; Chen, H.; Zhang, X. InfoGCL: Information-Aware Graph Contrastive Learning. In Proceedings of the Advances in Neural Information Processing Systems, Virtual, 28 October 2021; Volume 36, pp. 30414–30425. [Google Scholar]
- Fang, Y.; Fan, D.; Zha, D.; Tan, Q. GAugLLM: Improving Graph Contrastive Learning for Text-Attributed Graphs with Large Language Models. In Proceedings of the ACM SIGKDD International Conference on Knowledge Discovery and Data Mining 2024, Barcelona, Spain, 25–29 August 2024; pp. 747–758. [Google Scholar]
- Li, X.; Wang, B.; Wang, Y.; Wang, M. Graph-Based Text Classification by Contrastive Learning with Text-Level Graph Augmentation. ACM Trans. Knowl. Discov. Data 2024, 18, 1–21. [Google Scholar] [CrossRef] [Scilit]
- Wang, Z.; Li, Z.; Li, X.; Chen, W.; Liu, X. Graph-Based Contrastive Learning for Description and Detection of Local Features. IEEE Trans. Neural Netw. Learn. Syst. 2024, 35, 4839–4851. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Zhu, Y.; Shi, H.; Wang, X.; Liu, Y.; Wang, Y.; Peng, B.; Hong, C.; Tang, S. GraphCLIP: Enhancing Transferability in Graph Foundation Models for Text-Attributed Graphs; Association for Computing Machinery: New York, NY, USA, 2025; Volume 1, ISBN 9798400712746. [Google Scholar]
- Nikolentzos, G.; Vazirgiannis, M. Random Walk Graph Neural Networks. Adv. Neural Inf. Process. Syst. 2020, 33, 16211–16222. [Google Scholar]
- Fouss, F.; Pirotte, A.; Renders, J.M.; Saerens, M. Random-Walk Computation of Similarities between Nodes of a Graph with Application to Collaborative Recommendation. IEEE Trans. Knowl. Data Eng. 2007, 19, 355–369. [Google Scholar] [CrossRef] [Scilit]
- Wu, C.; Wang, C.; Xu, J.; Liu, Z.; Zheng, K.; Wang, X.; Song, Y.; Gai, K. Graph Contrastive Learning with Generative Adversarial Network. In Proceedings of the ACM SIGKDD International Conference on Knowledge Discovery and Data Mining, Long Beach, CA, USA, 6–10 August 2023; pp. 2721–2730. [Google Scholar] [CrossRef] [Scilit]
- Kipf, T.N.; Welling, M. Variational Graph Auto-Encoders. arXiv 2016, arXiv:1611.07308. [Google Scholar] [CrossRef] [Scilit]
- Hou, Z.; Liu, X.; Cen, Y.; Dong, Y.; Yang, H.; Wang, C.; Tang, J. GraphMAE: Self-Supervised Masked Graph Autoencoders. In Proceedings of the 28th ACM SIGKDD Conference on Knowledge Discovery and Data Mining, Washington, DC, USA, 14–18 August 2022; ACM: New York, NY, USA, 2022; pp. 594–604. [Google Scholar]
- Wang, C.; Pan, S.; Long, G.; Zhu, X.; Jiang, J. MGAE: Marginalized Graph Autoencoder for Graph Clustering. In Proceedings of the 2017 ACM on Conference on Information and Knowledge Management, Singapore, 6–10 November 2017; ACM: New York, NY, USA, 2017; Volume Part F1318, pp. 889–898. [Google Scholar]
- Tan, Q.; Liu, N.; Huang, X.; Choi, S.H.; Li, L.; Chen, R.; Hu, X. S2GAE: Self-Supervised Graph Autoencoders Are Generalizable Learners with Graph Masking. In Proceedings of the WSDM 2023—Proceedings of the 16th ACM International Conference on Web Search and Data Mining, Singapore, 27–28 February 2023; pp. 787–795. [Google Scholar] [CrossRef] [Scilit]
- Li, J.; Wu, R.; Sun, W.; Chen, L.; Tian, S.; Zhu, L.; Meng, C.; Zheng, Z.; Wang, W. What’s behind the Mask: Understanding Masked Graph Modeling for Graph Autoencoders. In Proceedings of the ACM SIGKDD International Conference on Knowledge Discovery and Data Mining, Long Beach, CA, USA, 6–10 August 2023; pp. 1268–1279. [Google Scholar] [CrossRef] [Scilit]
- Yi, H.C.; You, Z.H.; Huang, D.S.; Kwoh, C.K. Graph Representation Learning in Bioinformatics: Trends, Methods and Applications. Brief. Bioinform. 2022, 23, bbab340. [Google Scholar] [CrossRef] [Scilit]
- Zhang, X.M.; Liang, L.; Liu, L.; Tang, M.J. Graph Neural Networks and Their Current Applications in Bioinformatics. Front. Genet. 2021, 12, 690049. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Sun, L.; Zhang, Z.; Wang, F.; Ji, P.; Wen, J.; Su, S.; Yu, P.S. Aligning Dynamic Social Networks: An Optimization Over Dynamic Graph Autoencoder. IEEE Trans. Knowl. Data Eng. 2023, 35, 5597–5611. [Google Scholar] [CrossRef] [Scilit]
- Sun, Y.; Li, B.; Bi, X.; Feng, Q. Social Network Node Pricing Based on Graph Autoencoder in Data Marketplaces. Expert Syst. Appl. 2024, 243, 122815. [Google Scholar] [CrossRef] [Scilit]
- Fan, G.; Ma, Y.; Mei, X.; Fan, F.; Huang, J.; Ma, J. Hyperspectral Anomaly Detection with Robust Graph Autoencoders. IEEE Trans. Geosci. Remote Sens. 2022, 60, 5511314. [Google Scholar] [CrossRef] [Scilit]
- Ahmed, I.; Galoppo, T.; Hu, X.; Ding, Y. Graph Regularized Autoencoder and Its Application in Unsupervised Anomaly Detection. IEEE Trans. Pattern Anal. Mach. Intell. 2022, 44, 4110–4124. [Google Scholar] [CrossRef] [Scilit]
- Zhang, P.; Tu, S. MGAE-DC: Predicting the Synergistic Effects of Drug Combinations through Multi-Channel Graph Autoencoders. PLoS Comput. Biol. 2023, 19, e1010951. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Weiss, K.; Khoshgoftaar, T.M.; Wang, D.D. A Survey of Transfer Learning; Springer International Publishing: New York, NY, USA, 2016; Volume 3, ISBN 4053701600. [Google Scholar]
- Zhuang, F.; Qi, Z.; Duan, K.; Xi, D.; Zhu, Y.; Zhu, H.; Xiong, H.; He, Q. A Comprehensive Survey on Transfer Learning. Proc. IEEE 2021, 109, 43–76. [Google Scholar] [CrossRef] [Scilit]
- He, J.; Liu, Y.; Lawrence, R. Graph-Based Transfer Learning. In Proceedings of the 18th ACM Conference on Information and knowledge Management, Hong Kong, China, 2–6 November 2009; ACM: New York, NY, USA, 2009; pp. 937–946. [Google Scholar]
- Cai, C.; Wang, S.; Xu, Y.; Zhang, W.; Tang, K.; Ouyang, Q.; Lai, L.; Pei, J. Transfer Learning for Drug Discovery. J. Med. Chem. 2020, 63, 8683–8694. [Google Scholar] [CrossRef] [Scilit]
- Zhuang, D.; Ibrahim, A.K. Deep Learning for Drug Discovery: A Study of Identifying High Efficacy Drug Compounds Using a Cascade Transfer Learning Approach. Appl. Sci. 2021, 11, 7772. [Google Scholar] [CrossRef] [Scilit]
- Chen, X.; Hirota, K.; Dai, Y.; Wu, X. Ameliorated Graph Sample and Aggregate Network and Convolutional Neural Network for Stock Trading Decisions. Appl. Soft Comput. 2023, 145, 110626. [Google Scholar] [CrossRef] [Scilit]
- Zhang, S.; Tong, H.; Xu, J.; Maciejewski, R. Graph Convolutional Networks: A Comprehensive Review. Comput. Soc. Netw. 2019, 6, 11. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wu, F.; Zhang, T.; de Souza, A.H.; Fifty, C.; Yu, T.; Weinberger, K.Q. Simplifying Graph Convolutional Networks. In Proceedings of the 36th International Conference on Machine Learning, ICML, Long Beach, CA, USA, 9–15 June 2019; pp. 11884–11894. [Google Scholar]
- Zhang, Y.; Song, G.; Du, L.; Yang, S.; Jin, Y. DANE: Domain Adaptive Network Embedding. In Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, Macao, China, 10–16 August 2019; International Joint Conferences on Artificial Intelligence Organization: Pasadena, CA, USA, 2019; Volume 2019, pp. 4362–4368. [Google Scholar]
- Zhu, Q.; Yang, C.; Xu, Y.; Wang, H.; Zhang, C.; Han, J. Transfer Learning of Graph Neural Networks with Ego-Graph Information Maximization. Adv. Neural Inf. Process. Syst. 2021, 3, 1766–1779. [Google Scholar]
- Chen, J.; Yuan, Y.; Lang, H.; Ding, S.; Lu, J.J. The Improvement of Automated Crack Segmentation on Concrete Pavement with Graph Network. J. Adv. Transp. 2022, 2022, 2238095. [Google Scholar] [CrossRef] [Scilit]
- Hamilton, W.L.; Ying, R.; Leskovec, J. Inductive Representation Learning on Large Graphs. Adv. Neural Inf. Process. Syst. 2017, 30, 1025–1035. [Google Scholar]
- Crabtree, G.; Kócs, E.; Trahey, L. The Energy-Storage Frontier: Lithium-Ion Batteries and Beyond. MRS Bull. 2015, 40, 1067–1076. [Google Scholar] [CrossRef] [Scilit]
- Kim, S.; Jin, D.; Lee, H. Predicting Drug-Target Interactions Using Drug-Drug Interactions. PLoS ONE 2013, 8, e80129. [Google Scholar] [CrossRef] [Scilit]
- Lin, S.-F.; Xiao, K.-T.; Huang, Y.-T.; Chiu, C.-C.; Soo, V.-W. Analysis of Adverse Drug Reactions Using Drug and Drug Target Interactions and Graph-Based Methods. Artif. Intell. Med. 2010, 48, 161–166. [Google Scholar] [CrossRef] [Scilit]
- Pahikkala, T.; Airola, A.; Pietila, S.; Shakyawar, S.; Szwajda, A.; Tang, J.; Aittokallio, T. Toward More Realistic Drug-Target Interaction Predictions. Brief. Bioinform. 2015, 16, 325–337. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Liang, K.J.; Rangrej, S.B.; Petrovic, V.; Hassner, T. Few-Shot Learning with Noisy Labels. In Proceedings of the 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, LA, USA, 18–23 June 2022; IEEE: New York, NY, USA, 2022; Volume 2022, pp. 9079–9088. [Google Scholar]
- Lu, J.; Jin, S.; Liang, J.; Zhang, C. Robust Few-Shot Learning for User-Provided Data. IEEE Trans. Neural Netw. Learn. Syst. 2021, 32, 1433–1447. [Google Scholar] [CrossRef] [Scilit]
- Liu, J.; Song, L.; Qin, Y. Prototype Rectification for Few-Shot Learning. In Lecture Notes in Computer Science (Including Subseries Lecture Notes in Artificial Intelligence and Lecture Notes in Bioinformatics); Springer: New York, NY, USA, 2020; Volume 12346 LNCS, pp. 741–756. ISBN 9783030584511. [Google Scholar]
- Wu, Z.; Dadu, A.; Tustison, N.; Avants, B.; Nalls, M.; Sun, J.; Faghri, F. Multimodal Patient Representation Learning with Missing Modalities and Labels. In Proceedings of the The Twelfth International Conference on Learning Representations, Vienna, Austria, 7–11 May 2024. [Google Scholar]
- Garcia, V.; Bruna, J. Few-Shot Learning with Graph Neural Networks. In Proceedings of the 6th International Conference on Learning Representations, ICLR 2018—Conference Track Proceedings 2018, Vancouver, BC, Canada, 30 April–3 May 2018; pp. 1–13. [Google Scholar]
- Chen, J.; Mi, R.; Wang, H.; Wu, H.; Mo, J.; Guo, J.; Lai, Z.; Zhang, L.; Leung, V.C.M. A Review of Few-Shot and Zero-Shot Learning for Node Classification in Social Networks. IEEE Trans. Comput. Soc. Syst. 2025, 12, 1927–1941. [Google Scholar] [CrossRef] [Scilit]
- Chiang, P.Y.; Ni, R.; Miller, D.Y.; Bansal, A.; Geiping, J.; Goldblum, M.; Goldstein, T. Loss Landscapes Are All You Need: Neural Network Generalization Can Be Explained Without the Implicit Bias of Gradient Descent. In Proceedings of the 11th International Conference on Learning Representations, ICLR 2023, Kigali, Rwanda, 1–5 May 2023; pp. 1–16. [Google Scholar]
- Verpoort, P.C.; Lee, A.A.; Wales, D.J. Archetypal Landscapes for Deep Neural Networks. Proc. Natl. Acad. Sci. USA 2020, 117, 21857–21864. [Google Scholar] [CrossRef] [Scilit]
- Zhu, L.; Zhang, Z.; Song, D.; Chen, B. Analysis of Traffic Accident Causes Based on Data Augmentation and Ensemble Learning with High-Dimensional Small-Sample Data. Expert Syst. Appl. 2024, 237, 121782. [Google Scholar] [CrossRef] [Scilit]
- Shorten, C.; Khoshgoftaar, T.M. A Survey on Image Data Augmentation for Deep Learning. J. Big Data 2019, 6, 60. [Google Scholar] [CrossRef] [Scilit]
- Chlap, P.; Min, H.; Vandenberg, N.; Dowling, J.; Holloway, L.; Haworth, A. A Review of Medical Image Data Augmentation Techniques for Deep Learning Applications. J. Med. Imaging Radiat. Oncol. 2021, 65, 545–563. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Ding, K.; Xu, Z.; Tong, H.; Liu, H. Data Augmentation for Deep Graph Learning. ACM SIGKDD Explor. Newsl. 2022, 24, 61–77. [Google Scholar] [CrossRef] [Scilit]
- Moreno-Barea, F.J.; Jerez, J.M.; Franco, L. Improving Classification Accuracy Using Data Augmentation on Small Data Sets. Expert Syst. Appl. 2020, 161, 113696. [Google Scholar] [CrossRef] [Scilit]
- Yu, H.; Wang, Q.F.; Shi, J.Y. Data Augmentation Generated by Generative Adversarial Network for Small Sample Datasets Clustering. Neural Process. Lett. 2023, 55, 8365–8384. [Google Scholar] [CrossRef] [Scilit]
- Zhao, T.; Liu, Y.; Neves, L.; Woodford, O.; Jiang, M.; Shah, N. Data Augmentation for Graph Neural Networks. In Proceedings of the AAAI Conference on Artificial Intelligence 2021, Vancouver, BC, Canada, 2–9 February 2021; Volume 35, pp. 11015–11023. [Google Scholar] [CrossRef] [Scilit]
- Rebuffi, S.-A.; Gowal, S.; Calian, D.A.; Stimberg, F.; Wiles, O.; Mann, T. Data Augmentation Can Improve Robustness. Adv. Neural Inf. Process. Syst. 2021, 36, 29935–29948. [Google Scholar]
- Xia, J.; Wu, L.; Chen, J.; Hu, B.; Li, S.Z. SimGRACE: A Simple Framework for Graph Contrastive Learning without Data Augmentation. In Proceedings of the ACM Web Conference 2022, Lyon, France, 25–29 April 2022; ACM: New York, NY, USA, 2022; Volume 1, pp. 1070–1079. [Google Scholar]
- Liu, L.; Zhou, T.; Long, G.; Jiang, J.; Zhang, C. Learning to Propagate for Graph Meta-Learning. Adv. Neural Inf. Process. Syst. 2019, 32. [Google Scholar] [CrossRef] [Scilit]
- Fang, Y.; Wu, Y.; Yu, X.; Pan, S. Few-Shot Learning on Graphs: From Meta-Learning to LLM-Empowered Pre-Training and Beyond. In Proceedings of the Companion ACM on Web Conference 2025, Sydney, Australia, 28 April–2 May 2025; ACM: New York, NY, USA, 2025; pp. 9–12. [Google Scholar]
- Wang, H.; Zhao, H.; Li, B. Bridging Multi-Task Learning and Meta-Learning: Towards Efficient Training and Effective Adaptation. Proc. Mach. Learn. Res. 2021, 139, 10991–11002. [Google Scholar]
- Finn, C.; Rajeswaran, A.; Kakade, S.; Levine, S. Online Meta-Learning. In Proceedings of the 36th International Conference on Machine Learning, ICML 2019, Long Beach, CA, USA, 9–15 June 2019; Volume 2019, pp. 3398–3410. [Google Scholar]
- Schmidt, M. Least Squares Optimization with L1-Norm Regularization. CS542B Proj. Rep. 2005, 504, 195–221. [Google Scholar]
- Schmidt, M.; Fung, G.; Rosales, R. Fast Optimization Methods for L1 Regularization: A Comparative Study and Two New Approaches. In Machine Learning: ECML 2007; Springer: Berlin/Heidelberg, Germany, 2007; Volume 4701 LNAI, pp. 286–297. ISBN 9783540749578. [Google Scholar]
- Papp, P.A.; Martinkus, K.; Faber, L.; Wattenhofer, R. DropGNN: Random Dropouts Increase the Expressiveness of Graph Neural Networks. Adv. Neural Inf. Process. Syst. 2021, 26, 21997–22009. [Google Scholar]
- Hang, T.; Wu, W.; Feng, J.; Djigal, H.; Huang, J. A Survey of Few-Shot Relation Extraction Combining Meta-Learning with Prompt Learning. Neurocomputing 2025, 647, 130534. [Google Scholar] [CrossRef] [Scilit]
- Lee, J.; Lee, I.; Kang, J. Self-Attention Graph Pooling. In Proceedings of the 36th International Conference on Machine Learning, ICML 2019, Long Beach, CA, USA, 9–15 June 2019; pp. 6661–6670. [Google Scholar]
- Guo, D.; Shao, Y.; Cui, Y.; Wang, Z.; Zhang, L.; Shen, C. Graph Attention Tracking. In Proceedings of the 2021 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Nashville, TN, USA, 19–23 June 2021; IEEE: New York, NY, USA, 2021; pp. 9538–9547. [Google Scholar]
- Chen, X.; Jia, S.; Xiang, Y. A Review: Knowledge Reasoning over Knowledge Graph. Expert Syst. Appl. 2020, 141, 112948. [Google Scholar] [CrossRef] [Scilit]
- Chen, Z.; Wang, Y.; Zhao, B.; Cheng, J.; Zhao, X.; Duan, Z. Knowledge Graph Completion: A Review. IEEE Access 2020, 8, 192435–192456. [Google Scholar] [CrossRef] [Scilit]
- Manthiram, A. An Outlook on Lithium Ion Battery Technology. ACS Cent. Sci. 2017, 3, 1063–1069. [Google Scholar] [CrossRef] [Scilit]
- Famprikis, T.; Canepa, P.; Dawson, J.A.; Islam, M.S.; Masquelier, C. Fundamentals of Inorganic Solid-State Electrolytes for Batteries. Nat. Mater. 2019, 18, 1278–1291. [Google Scholar] [CrossRef] [Scilit]
- Müller, S.; Sauter, C.; Shunmugasundaram, R.; Wenzler, N.; De Andrade, V.; De Carlo, F.; Konukoglu, E.; Wood, V. Deep Learning-Based Segmentation of Lithium-Ion Battery Microstructures Enhanced by Artificially Generated Electrodes. Nat. Commun. 2021, 12, 6205. [Google Scholar] [CrossRef] [Scilit]
- Rothgang, S.; Baumhöfer, T.; van Hoek, H.; Lange, T.; De Doncker, R.W.; Sauer, D.U. Modular Battery Design for Reliable, Flexible and Multi-Technology Energy Storage Systems. Appl. Energy 2015, 137, 931–937. [Google Scholar] [CrossRef] [Scilit]
- Campestrini, C.; Keil, P.; Schuster, S.F.; Jossen, A. Ageing of Lithium-Ion Battery Modules with Dissipative Balancing Compared with Single-Cell Ageing. J. Energy Storage 2016, 6, 142–152. [Google Scholar] [CrossRef] [Scilit]
- Xu, H.; Shen, M. The Control of Lithium-ion Batteries and Supercapacitors in Hybrid Energy Storage Systems for Electric Vehicles: A Review. Int. J. Energy Res. 2021, 45, 20524–20544. [Google Scholar] [CrossRef] [Scilit]
- Thelen, A.; Huan, X.; Paulson, N.; Onori, S.; Hu, Z.; Hu, C. Probabilistic Machine Learning for Battery Health Diagnostics and Prognostics—Review and Perspectives. npj Mater. Sustain. 2024, 2, 14. [Google Scholar] [CrossRef] [Scilit]
- Tang, K.; Luo, B.; Chen, D.; Wang, C.; Chen, L.; Li, F.; Cao, Y.; Wang, C. The State of Health Estimation of Lithium-Ion Batteries: A Review of Health Indicators, Estimation Methods, Development Trends and Challenges. World Electr. Veh. J. 2025, 16, 429. [Google Scholar] [CrossRef] [Scilit]
- Liu, Y.; He, Y.; Bian, H.; Guo, W.; Zhang, X. A Review of Lithium-Ion Battery State of Charge Estimation Based on Deep Learning: Directions for Improvement and Future Trends. J. Energy Storage 2022, 52, 104664. [Google Scholar] [CrossRef] [Scilit]
- Shu, X.; Shen, S.; Shen, J.; Zhang, Y.; Li, G.; Chen, Z.; Liu, Y. State of Health Prediction of Lithium-Ion Batteries Based on Machine Learning: Advances and Perspectives. iScience 2021, 24, 103265. [Google Scholar] [CrossRef] [Scilit]
- Deng, Z.; Lin, X.; Cai, J.; Hu, X. Battery Health Estimation with Degradation Pattern Recognition and Transfer Learning. J. Power Sources 2022, 525, 231027. [Google Scholar] [CrossRef] [Scilit]
- Zheng, Q.; Wang, R.; Tian, X.; Yu, Z.; Wang, H.; Elhanashi, A.; Saponara, S. A Real-Time Transformer Discharge Pattern Recognition Method Based on CNN-LSTM Driven by Few-Shot Learning. Electr. Power Syst. Res. 2023, 219, 109241. [Google Scholar] [CrossRef] [Scilit]
- Krewer, U.; Röder, F.; Harinath, E.; Braatz, R.D.; Bedürftig, B.; Findeisen, R. Review—Dynamic Models of Li-Ion Batteries for Diagnosis and Operation: A Review and Perspective. J. Electrochem. Soc. 2018, 165, A3656–A3673. [Google Scholar] [CrossRef] [Scilit]
- Guo, N.; Chen, S.; Tao, J.; Liu, Y.; Wan, J.; Li, X. Semi-Supervised Learning for Explainable Few-Shot Battery Lifetime Prediction. Joule 2024, 8, 1820–1836. [Google Scholar] [CrossRef] [Scilit]
- Yao, X.-Y.Y.; Chen, G.; Pecht, M.; Chen, B. A Novel Graph-Based Framework for State of Health Prediction of Lithium-Ion Battery. J. Energy Storage 2023, 58, 106437. [Google Scholar] [CrossRef] [Scilit]
- Wu, W.; Chen, Z.; Liu, W.; Pan, E. Correlation Based-Graph Neural Network for Health Prognosis of Non-Fully Charged and Discharged Lithium-Ion Batteries. J. Power Sources 2025, 629, 235984. [Google Scholar] [CrossRef] [Scilit]
- Yang, J.; Wang, X.; Zhang, M.; Jiang, L. Bayesian Meta Random Graph Implicit Enhanced Network for Lithium-Ion Batteries Remaining Useful Life Prediction With Few-Shot and Uncertainty Interference. IEEE Trans. Transp. Electrif. 2025, 11, 9877–9889. [Google Scholar] [CrossRef] [Scilit]
- Kim, W.H.; Chung, Y.M.; Stinner, B. State of Health Prediction of Lithium-Ion Batteries with Adaptive Loss-Based Graph Neural Network. J. Energy Storage 2025, 124, 116637. [Google Scholar] [CrossRef] [Scilit]
- Harinarayanan, J.; Balamurugan, P. SOC Estimation for a Lithium-Ion Pouch Cell Using Machine Learning under Different Load Profiles. Sci. Rep. 2025, 15, 18091. [Google Scholar] [CrossRef] [Scilit]
- Lu, J.; Xiong, R.; Tian, J.; Wang, C.; Sun, F. Deep Learning to Estimate Lithium-Ion Battery State of Health without Additional Degradation Experiments. Nat. Commun. 2023, 14, 2760. [Google Scholar] [CrossRef] [Scilit]
- Zhao, F.M.; Gao, D.X.; Cheng, Y.M.; Yang, Q. Estimation of Lithium-Ion Battery Health State Using MHATTCN Network with Multi-Health Indicators Inputs. Sci. Rep. 2024, 14, 18391. [Google Scholar] [CrossRef] [Scilit]
- Rout, S.; Samal, S.K.; Gelmecha, D.J.; Mishra, S. Estimation of State of Health for Lithium-Ion Batteries Using Advanced Data-Driven Techniques. Sci. Rep. 2025, 15, 30428. [Google Scholar] [CrossRef] [Scilit]
- Jerouschek, D.; Tan, Ö.; Kennel, R.; Taskiran, A. Data Preparation and Training Methodology for Modeling Lithium-Ion Batteries Using a Long Short-Term Memory Neural Network for Mild-Hybrid Vehicle Applications. Appl. Sci. 2020, 10, 7880. [Google Scholar] [CrossRef] [Scilit]
- Zhao, F.M.; Gao, D.X.; Cheng, Y.M.; Yang, Q. Application of State of Health Estimation and Remaining Useful Life Prediction for Lithium-Ion Batteries Based on AT-CNN-BiLSTM. Sci. Rep. 2024, 14, 29026. [Google Scholar] [CrossRef] [Scilit]
- Shen, S.; Sadoughi, M.; Chen, X.; Hong, M.; Hu, C. A Deep Learning Method for Online Capacity Estimation of Lithium-Ion Batteries. J. Energy Storage 2019, 25, 100817. [Google Scholar] [CrossRef] [Scilit]
- Wang, Y.X.; Chen, Z.; Zhang, W. Lithium-Ion Battery State-of-Charge Estimation for Small Target Sample Sets Using the Improved GRU-Based Transfer Learning. Energy 2022, 244, 123178. [Google Scholar] [CrossRef] [Scilit]
- Zhou, K.Q.; Qin, Y.; Yuen, C. Graph Neural Network-Based Lithium-Ion Battery State of Health Estimation Using Partial Discharging Curve. J. Energy Storage 2024, 100, 113502. [Google Scholar] [CrossRef] [Scilit]
- Guo, R.; Zhang, K.; He, S.; Tao, S.; Zhang, X.; Liu, K.; Li, X.; Tian, J.; Shen, W.; Chung, C.Y. Robust Health Monitoring for Lithium-Ion Batteries Under Guidance of Proxy Labels: A Deep Multitask Learning Approach. IEEE Trans. Power Electron. 2025, 40, 10272–10285. [Google Scholar] [CrossRef] [Scilit]
- Fan, Q.; He, G.; Ruan, D.; Gühmann, C. Multi-Expert Fusion for State-of-Health Estimation of Lithium-Ion Batteries. Sci. Rep. 2025, 15, 42058. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Fan, Y.; Lin, Z.; Wang, F.; Zhang, J. A Hybrid Approach for Lithium-Ion Battery Remaining Useful Life Prediction Using Signal Decomposition and Machine Learning. Sci. Rep. 2025, 15, 8161. [Google Scholar] [CrossRef] [Scilit]
- Hannan, M.A.; How, D.N.T.; Lipu, M.S.H.; Mansor, M.; Ker, P.J.; Dong, Z.Y.; Sahari, K.S.M.; Tiong, S.K.; Muttaqi, K.M.; Mahlia, T.M.I.; et al. Deep Learning Approach towards Accurate State of Charge Estimation for Lithium-Ion Batteries Using Self-Supervised Transformer Model. Sci. Rep. 2021, 11, 19541. [Google Scholar] [CrossRef] [Scilit]
- Zhang, S.; Liu, Z.; Su, H. State of Health Estimation for Lithium-Ion Batteries on Few-Shot Learning. Energy 2023, 268, 126726. [Google Scholar] [CrossRef] [Scilit]
- Xiong, Y.; He, T.; Zhu, W.; Liao, Y.; Xu, Q.; Niu, Y.; Chen, Z. The State of Charge Predication of Lithium-Ion Battery Energy Storage System Using Contrastive Learning. Sustain. Energy Technol. Assess. 2024, 71, 103989. [Google Scholar] [CrossRef] [Scilit]
- Shen, Y.; Guo, D.; Wang, Y.; Chen, J.; Liu, X.; Han, X.; Zheng, Y.; Ouyang, M. Enhanced Few-Shot State-of-Health Estimation for Lithium-Ion Batteries via Masked Autoencoder. Energy 2025, 335, 138263. [Google Scholar] [CrossRef] [Scilit]
- Yin, Y.; Gao, Z.; Huang, Y.; Liu, Q. PLT-GRU: Physics-Informed Lightweight Transformer-GRU Algorithm for Few-Shot Battery State-of-Health Estimation. Meas. Sci. Technol. 2025, 36, 096216. [Google Scholar] [CrossRef] [Scilit]
- Jiang, R.; Wang, C.; Xie, H.; Lu, X.; Wang, C.; Yu, Q. Few-Shot Learning Resolves Data Scarcity in Sodium-Ion Battery State of Heath Estimation 2025. Available online: https://ssrn.com/abstract=5548898 (accessed on 30 September 2025).
- Li, X.; Xu, J.; Ding, X.; Lyu, H. State of Charge Estimation for Batteries Based on Common Feature Extraction and Transfer Learning. Batteries 2023, 9, 266. [Google Scholar] [CrossRef] [Scilit]
- Tao, S.; Liu, H.; Sun, C.; Ji, H.; Ji, G.; Han, Z.; Gao, R.; Ma, J.; Ma, R.; Chen, Y.; et al. Collaborative and Privacy-Preserving Retired Battery Sorting for Profitable Direct Recycling via Federated Machine Learning. Nat. Commun. 2023, 14, 8032. [Google Scholar] [CrossRef] [Scilit]
- Wong, K.L.; Tse, R.; Tang, S.-K.K.; Pau, G. Decentralized Deep-Learning Approach for Lithium-Ion Batteries State of Health Forecasting Using Federated Learning. IEEE Trans. Transp. Electrif. 2024, 10, 8199–8212. [Google Scholar] [CrossRef] [Scilit]
- Tao, S.; Guo, R.; Lee, J.; Moura, S.; Casals, L.C.; Jiang, S.; Shi, J.; Harris, S.; Zhang, T.; Chung, C.Y.; et al. Immediate Remaining Capacity Estimation of Heterogeneous Second-Life Lithium-Ion Batteries via Deep Generative Transfer Learning. Energy Environ. Sci. 2025, 18, 7413–7426. [Google Scholar] [CrossRef] [Scilit]
- Tang, X.; Liu, Y.; Lai, X. Lifespan-Based Battery Classification towards Second-Life Utilization. In Proceedings of the 2024 IEEE 25th China Conference on System Simulation Technology and its Application, CCSSTA 2024, Tianjin, China, 21–23 July 2024; pp. 591–594. [Google Scholar] [CrossRef] [Scilit]
- Tang, X.; Lai, X.; Zou, C.; Zhou, Y.; Zhu, J.; Zheng, Y.; Gao, F. Detecting Abnormality of Battery Lifetime from First-Cycle Data Using Few-Shot Learning. Adv. Sci. 2024, 11, 2305315. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Meng, J.; You, Y.; Lin, M.; Wu, J.; Song, Z. Multi-Scenarios Transferable Learning Framework with Few-Shot for Early Lithium-Ion Battery Lifespan Trajectory Prediction. Energy 2024, 286, 129682. [Google Scholar] [CrossRef] [Scilit]
- Sui, X.; He, S.; Zheng, Y.; Che, Y.; Teodorescu, R. Early Prediction of Lithium-Ion Batteries Lifetime via Few-Shot Learning. In Proceedings of the IECON Proceedings (Industrial Electronics Conference) 2023, Singapore, 16–19 October 2023; pp. 1–6. [Google Scholar] [CrossRef] [Scilit]
- Shu, X.; Shen, J.; Guo, F.; Liu, Y.; Zhang, Y.; Chen, Z.; Zhao, H. Towards Real-World Battery Health Intelligence: A Review of Machine Learning Advances and Challenges in SOH Estimation. eTransportation 2025, 26, 100509. [Google Scholar] [CrossRef] [Scilit]
- Yan, K.; Lu, J.; Zeng, D.; Cheng, L.; Ma, T. Bayesian Deep Learning for Vehicle Battery Health Prognostics: Incorporating Behavioral Perception and Informative Priors. J. Energy Storage 2026, 143, 119659. [Google Scholar] [CrossRef] [Scilit]
- Zhao, X.; Wang, Z.; Han, T.; Yang, W.; Gu, F.; Ball, A.D. A Meta-Learning Method for Few-Shot Multidomain State-of-Health Estimation of Lithium-Ion Batteries. IEEE Trans. Transp. Electrif. 2025, 11, 4830–4840. [Google Scholar] [CrossRef] [Scilit]
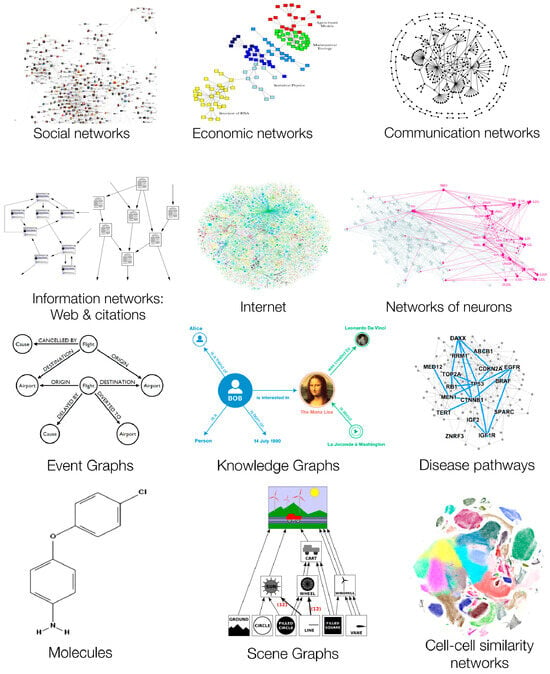
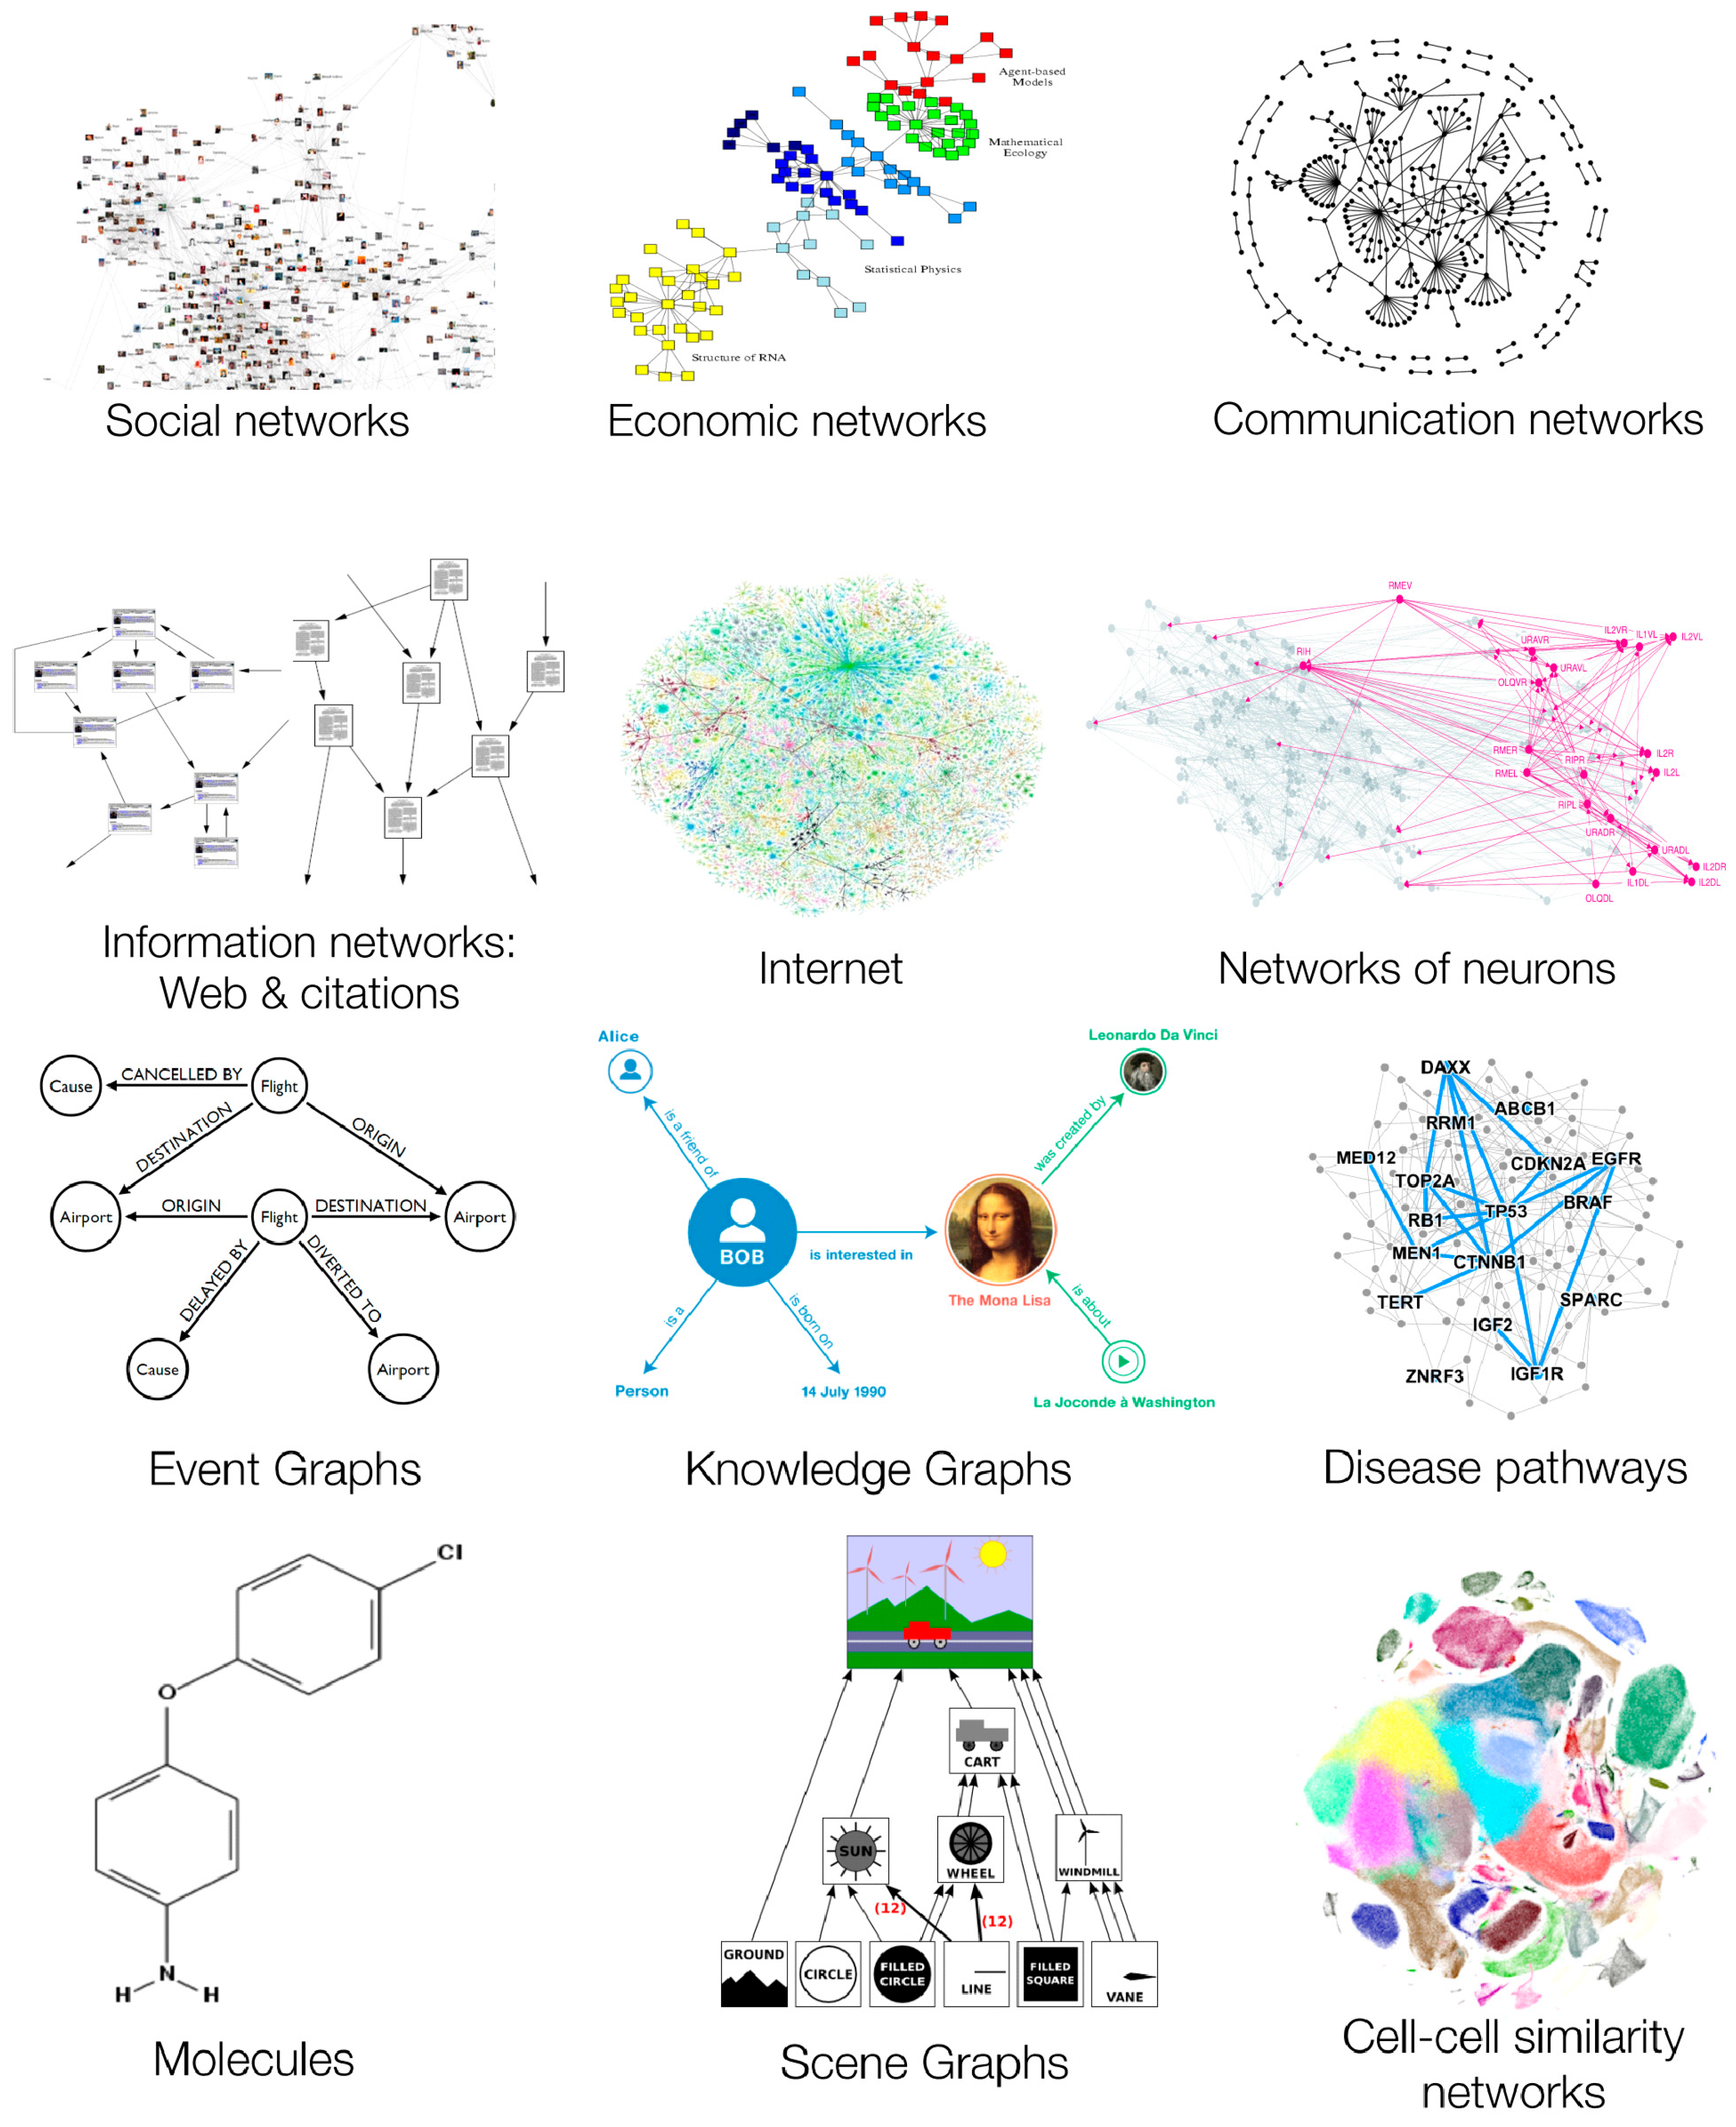
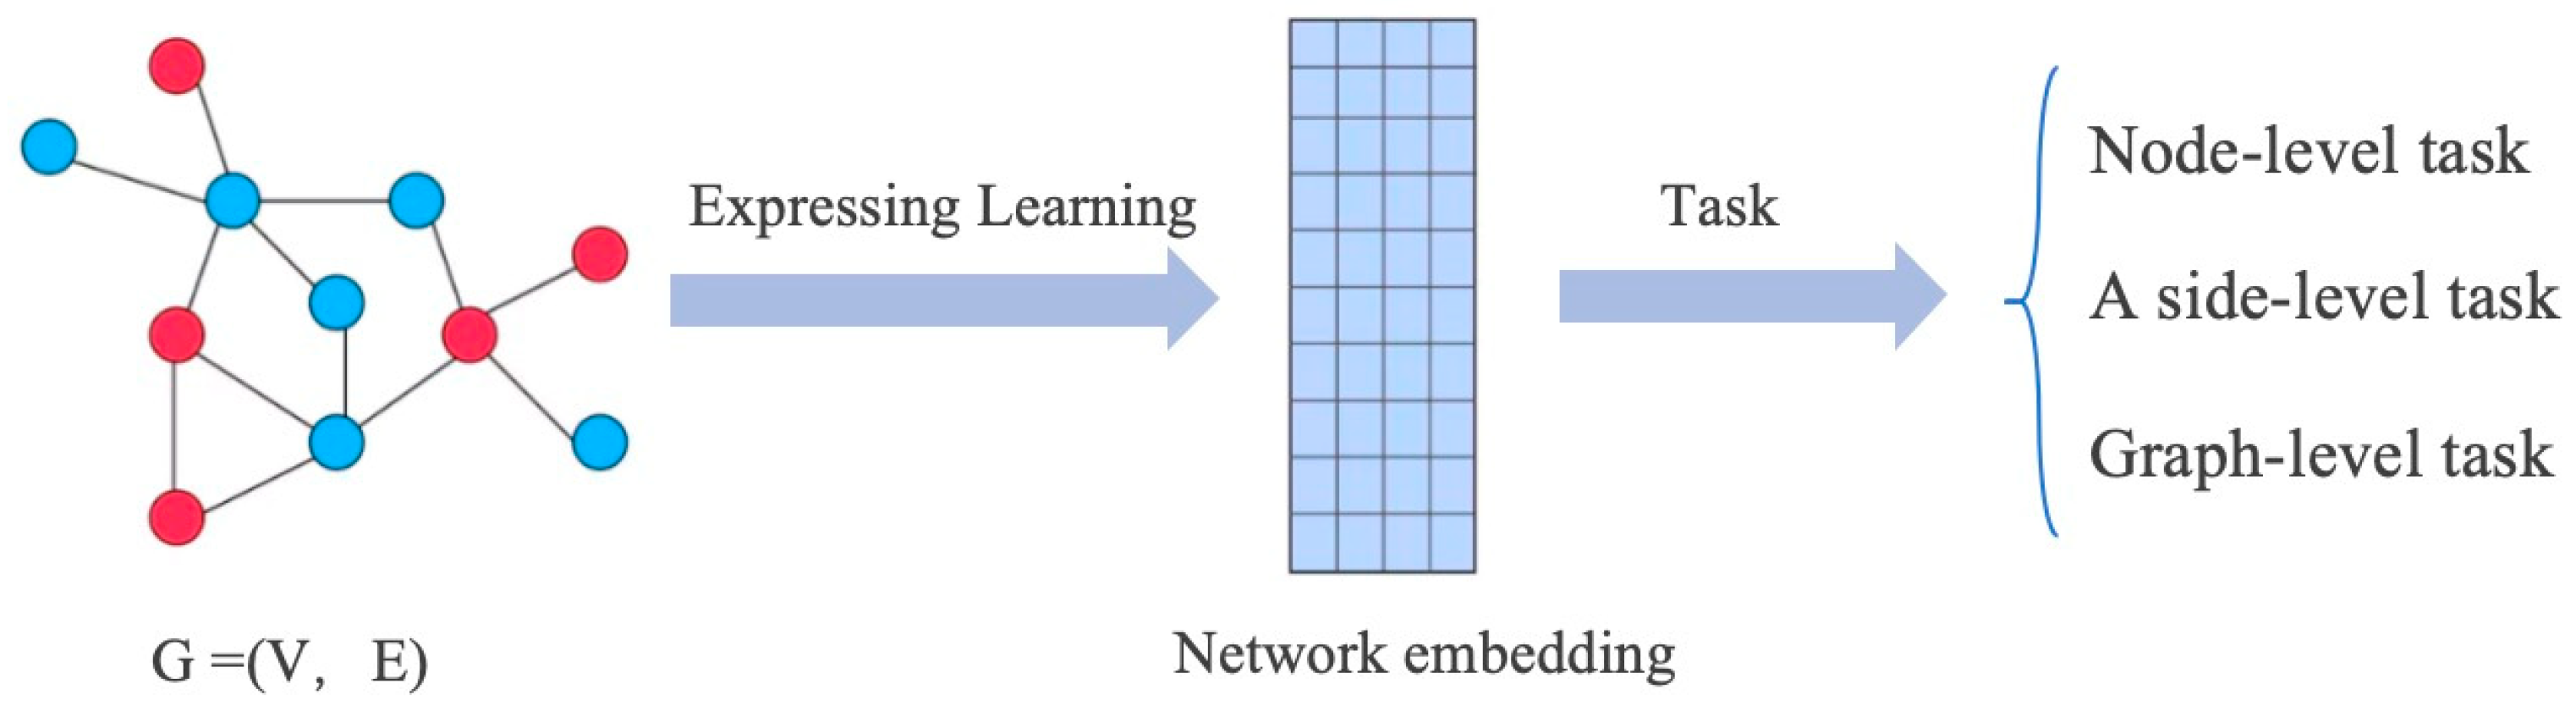
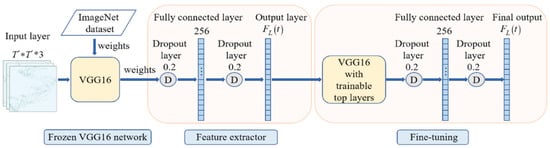
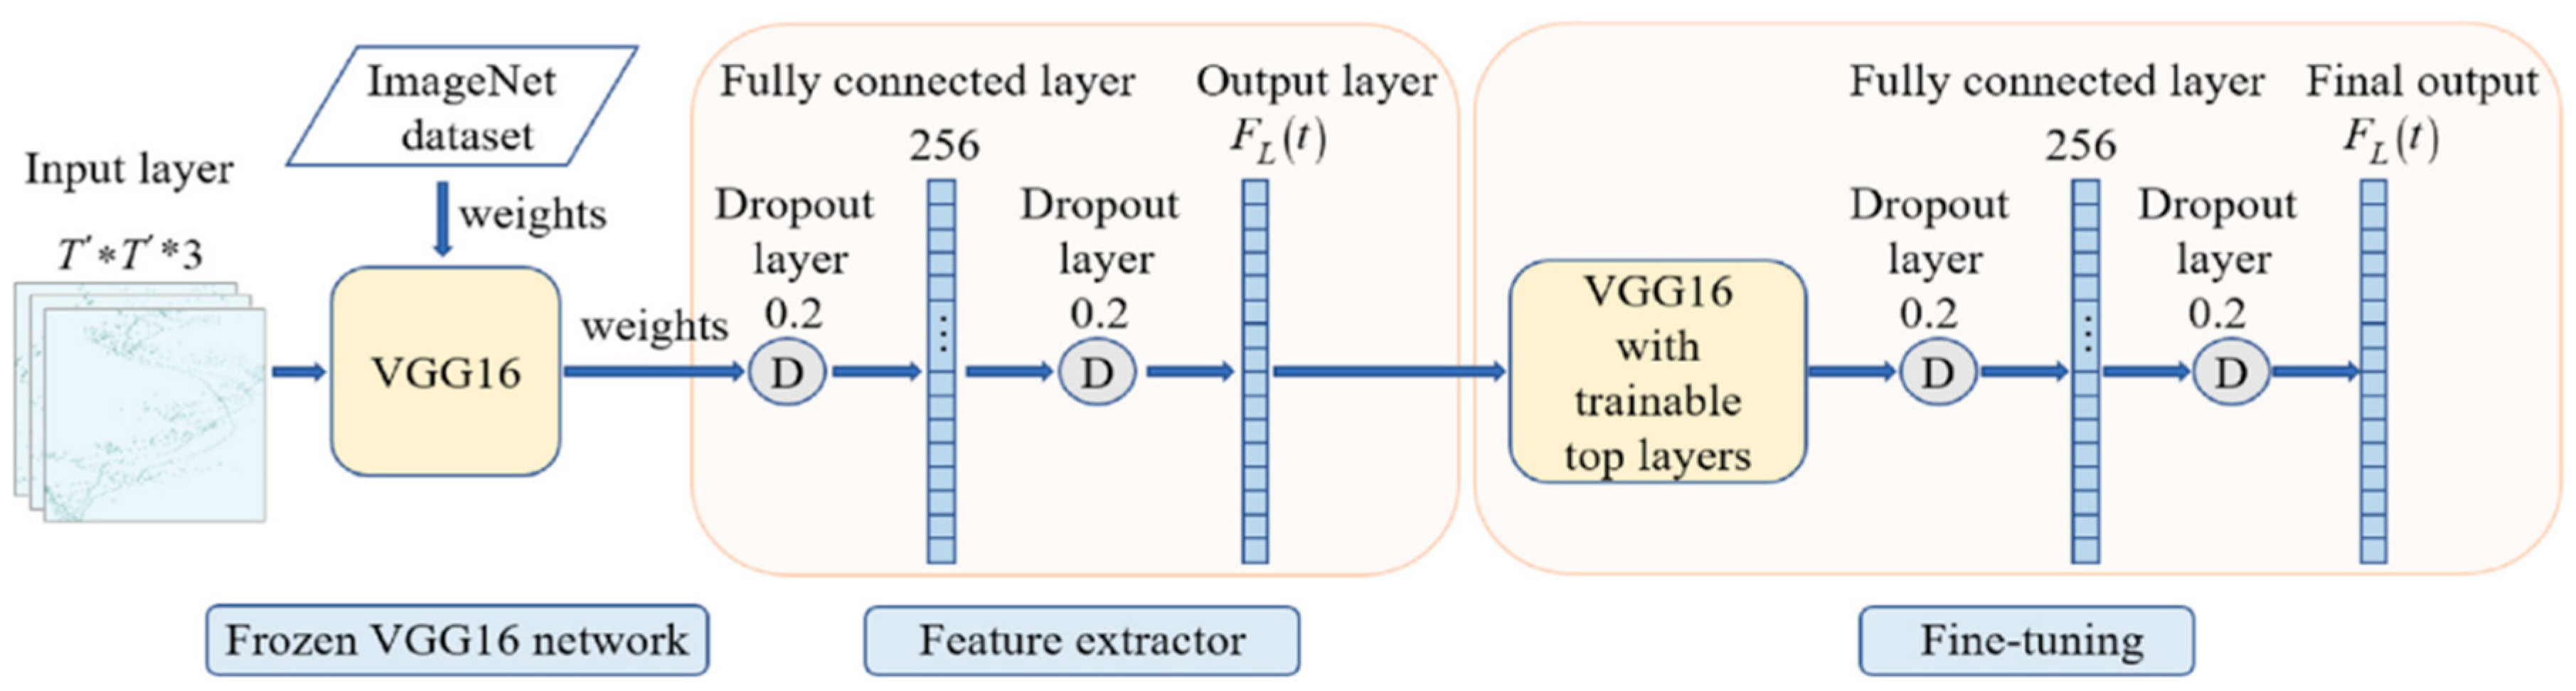
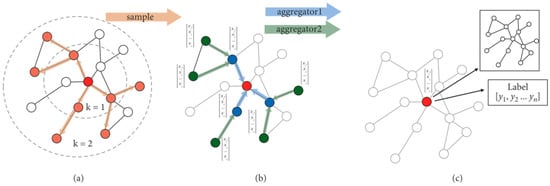
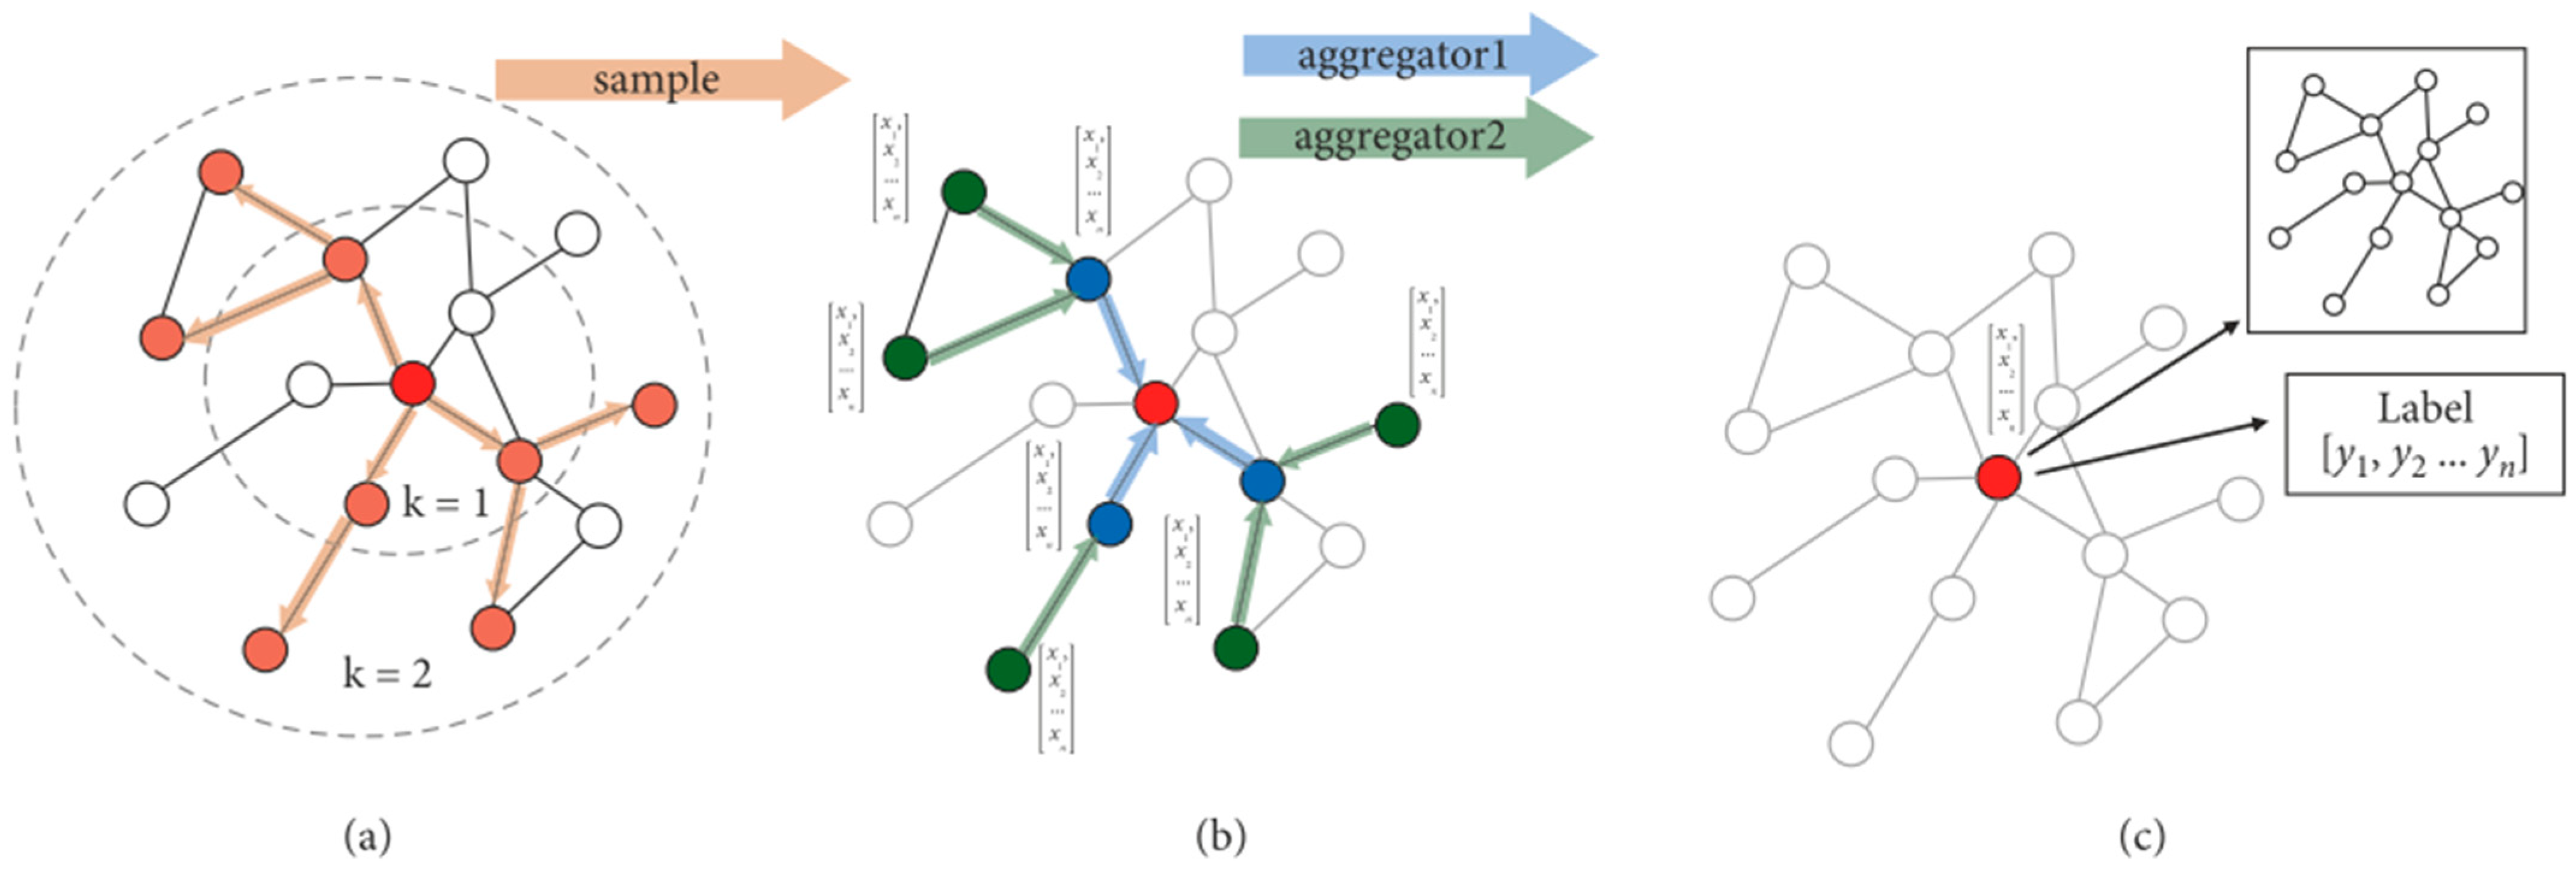
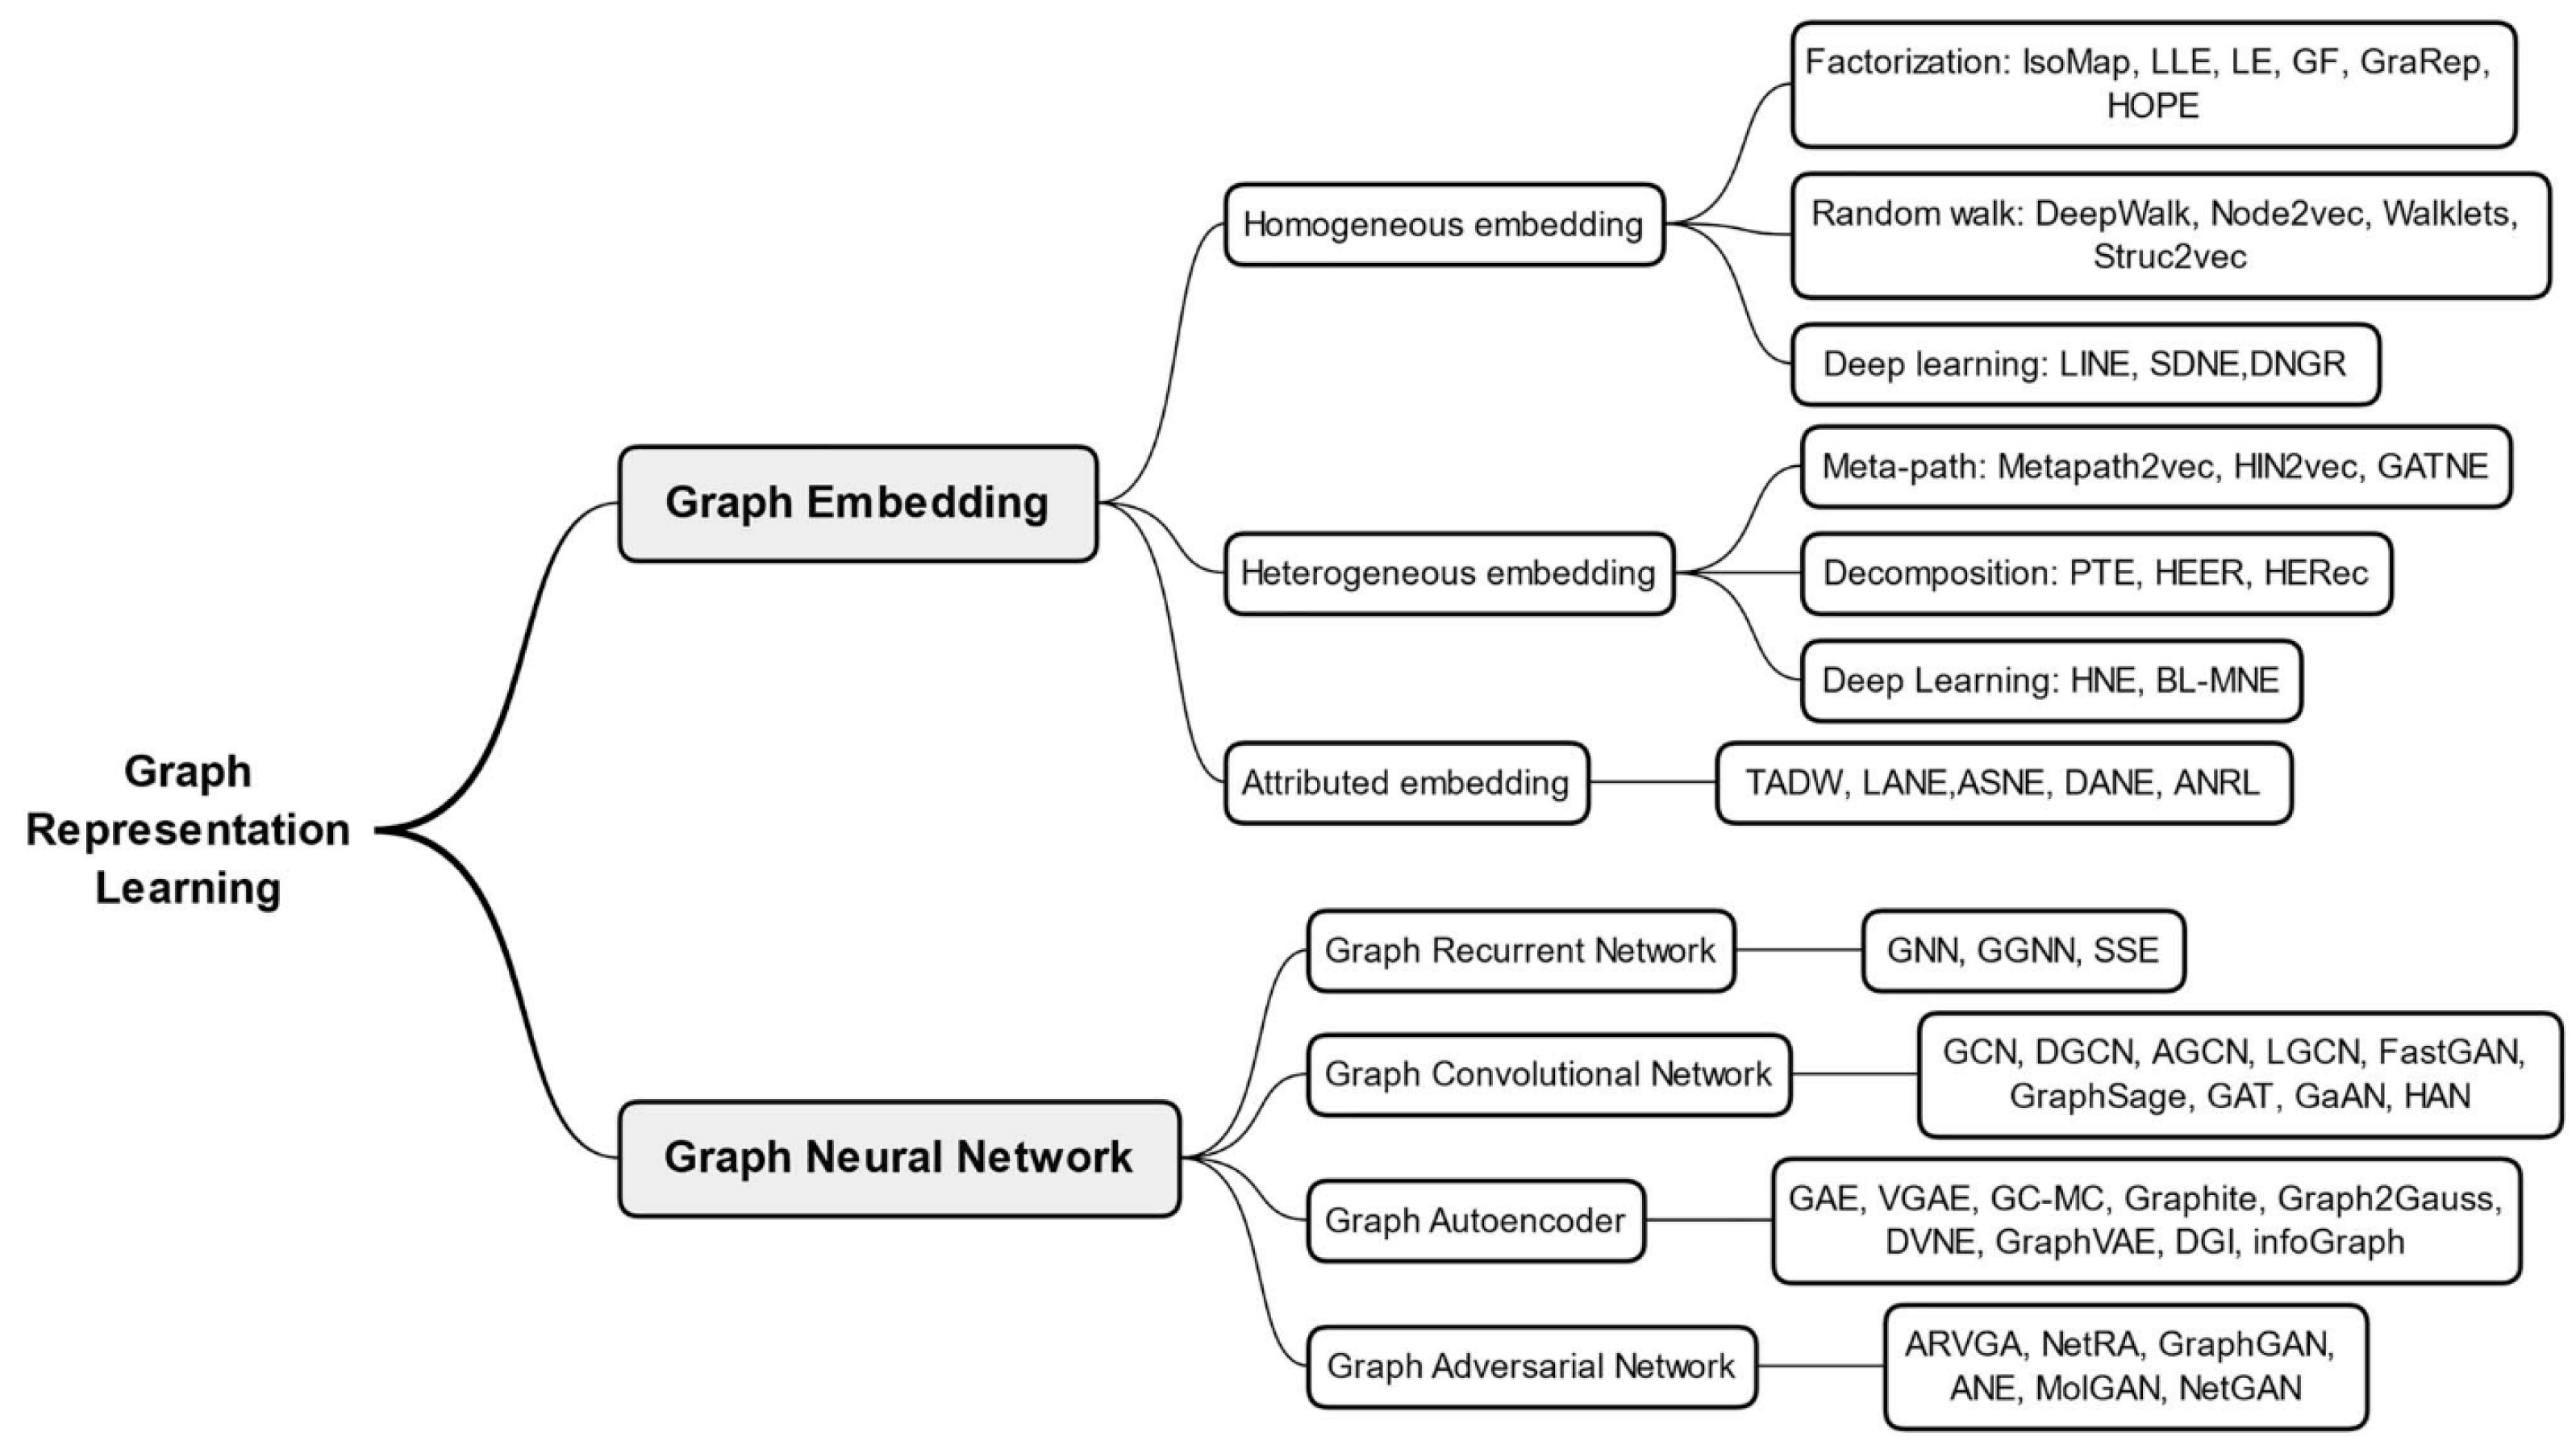
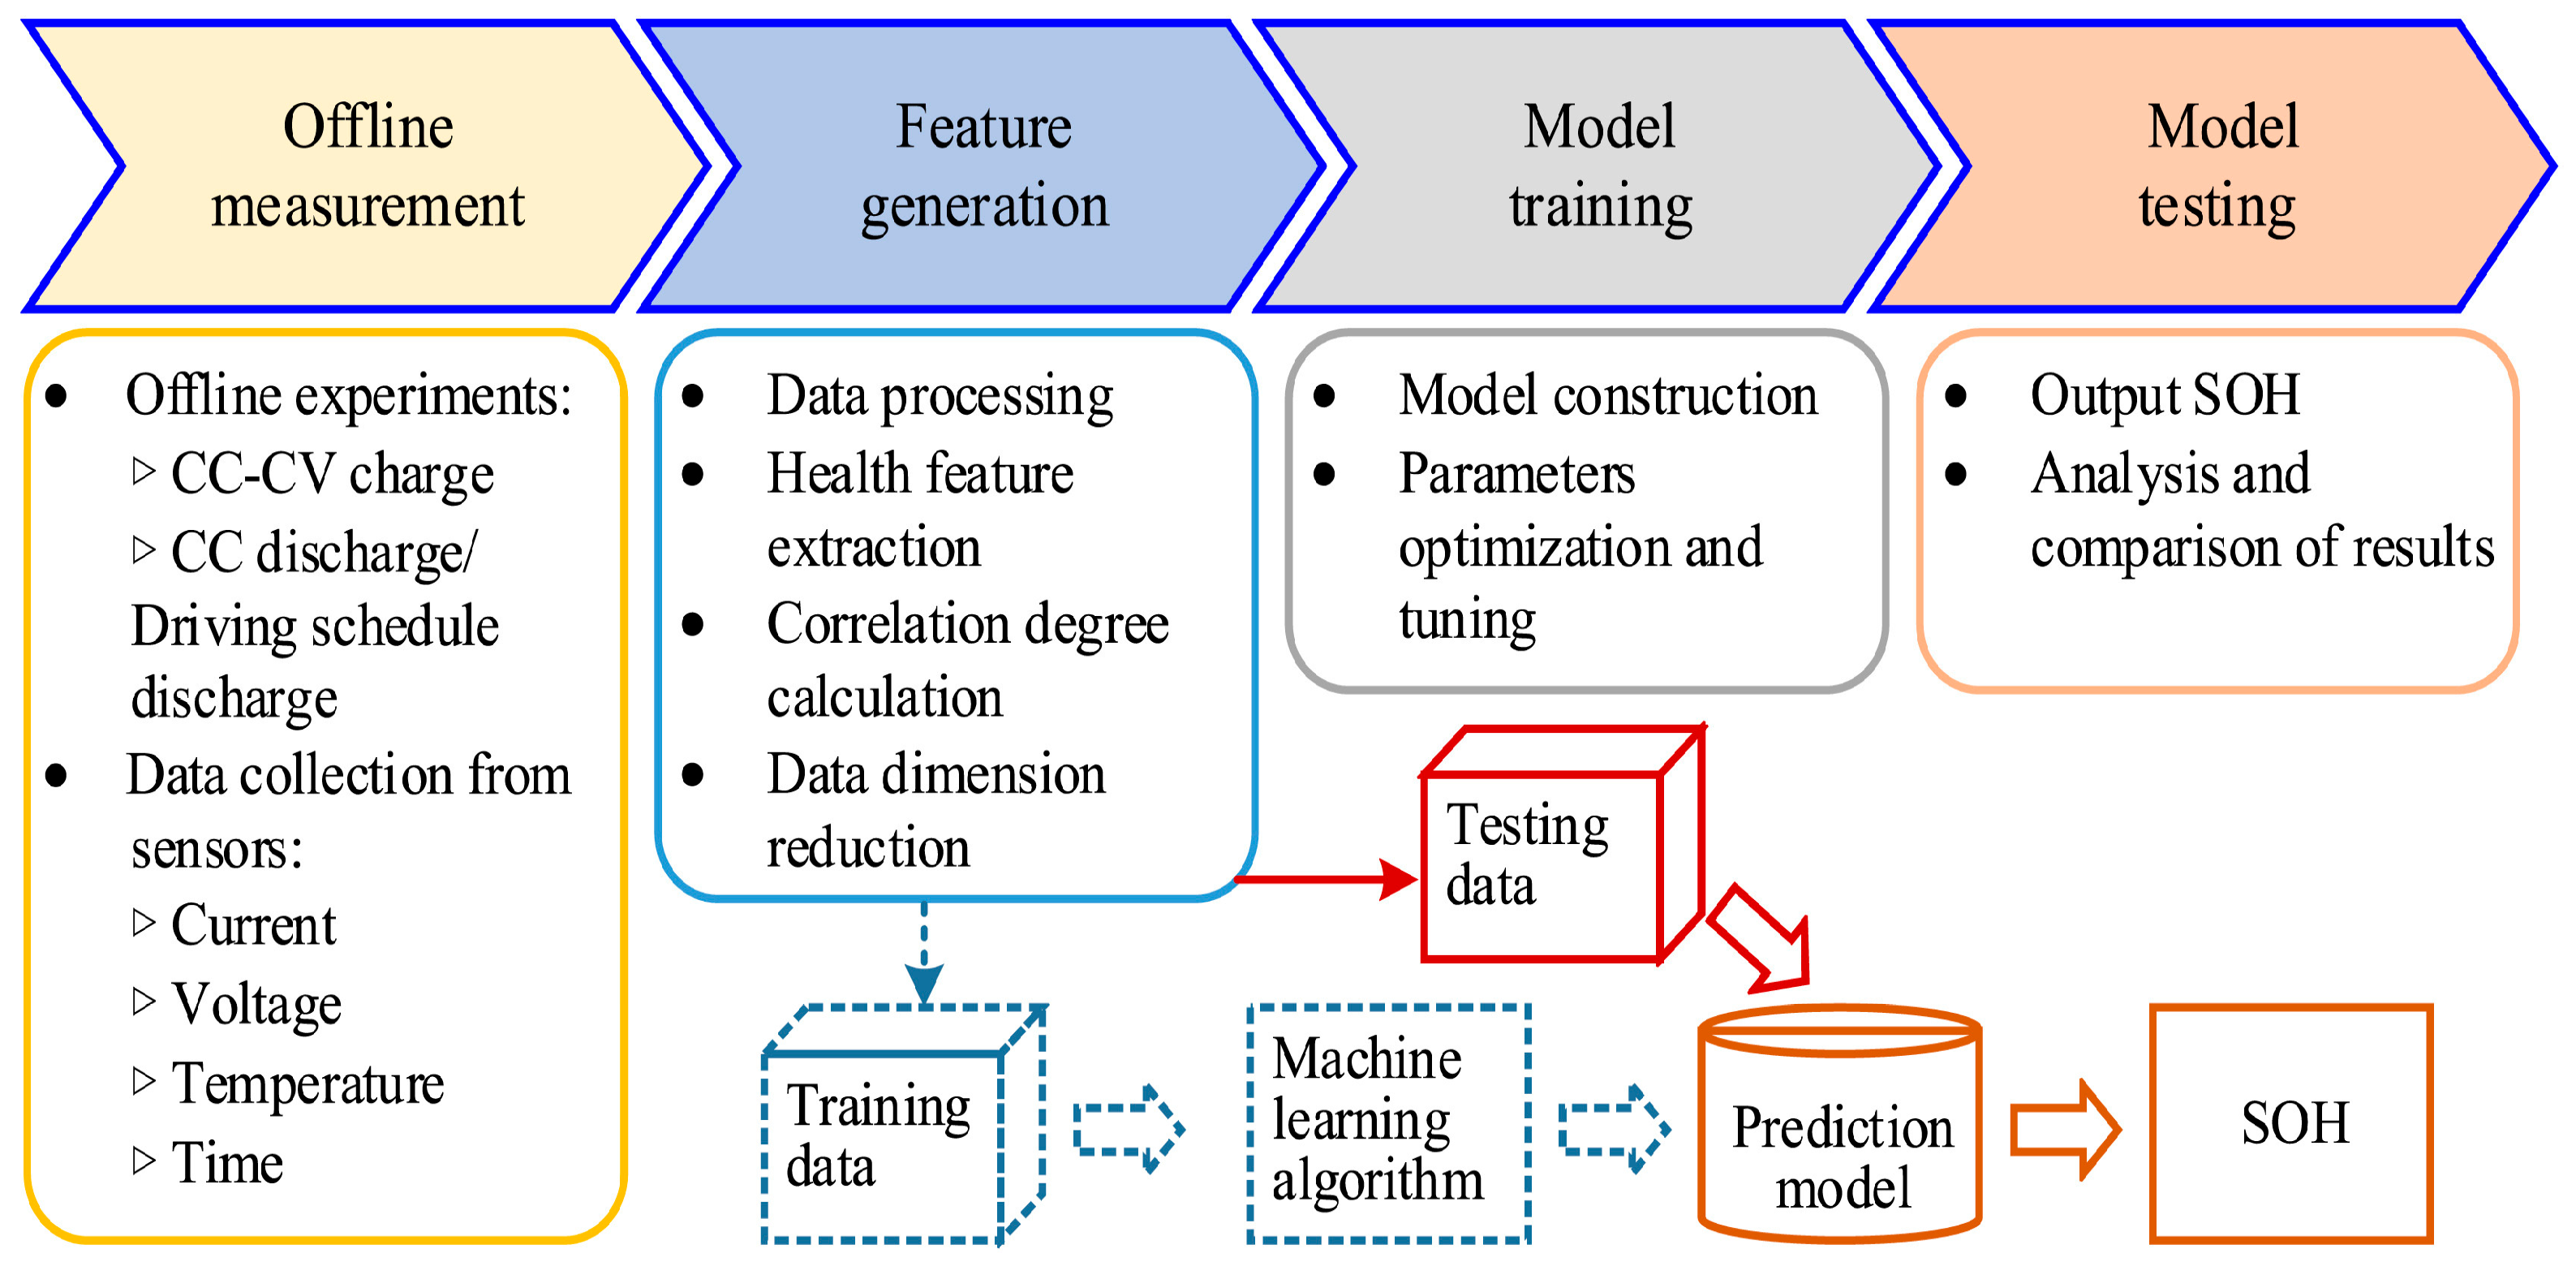
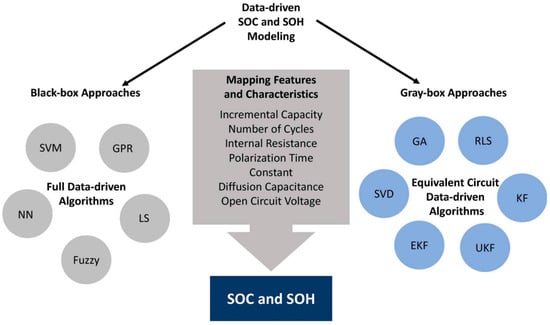
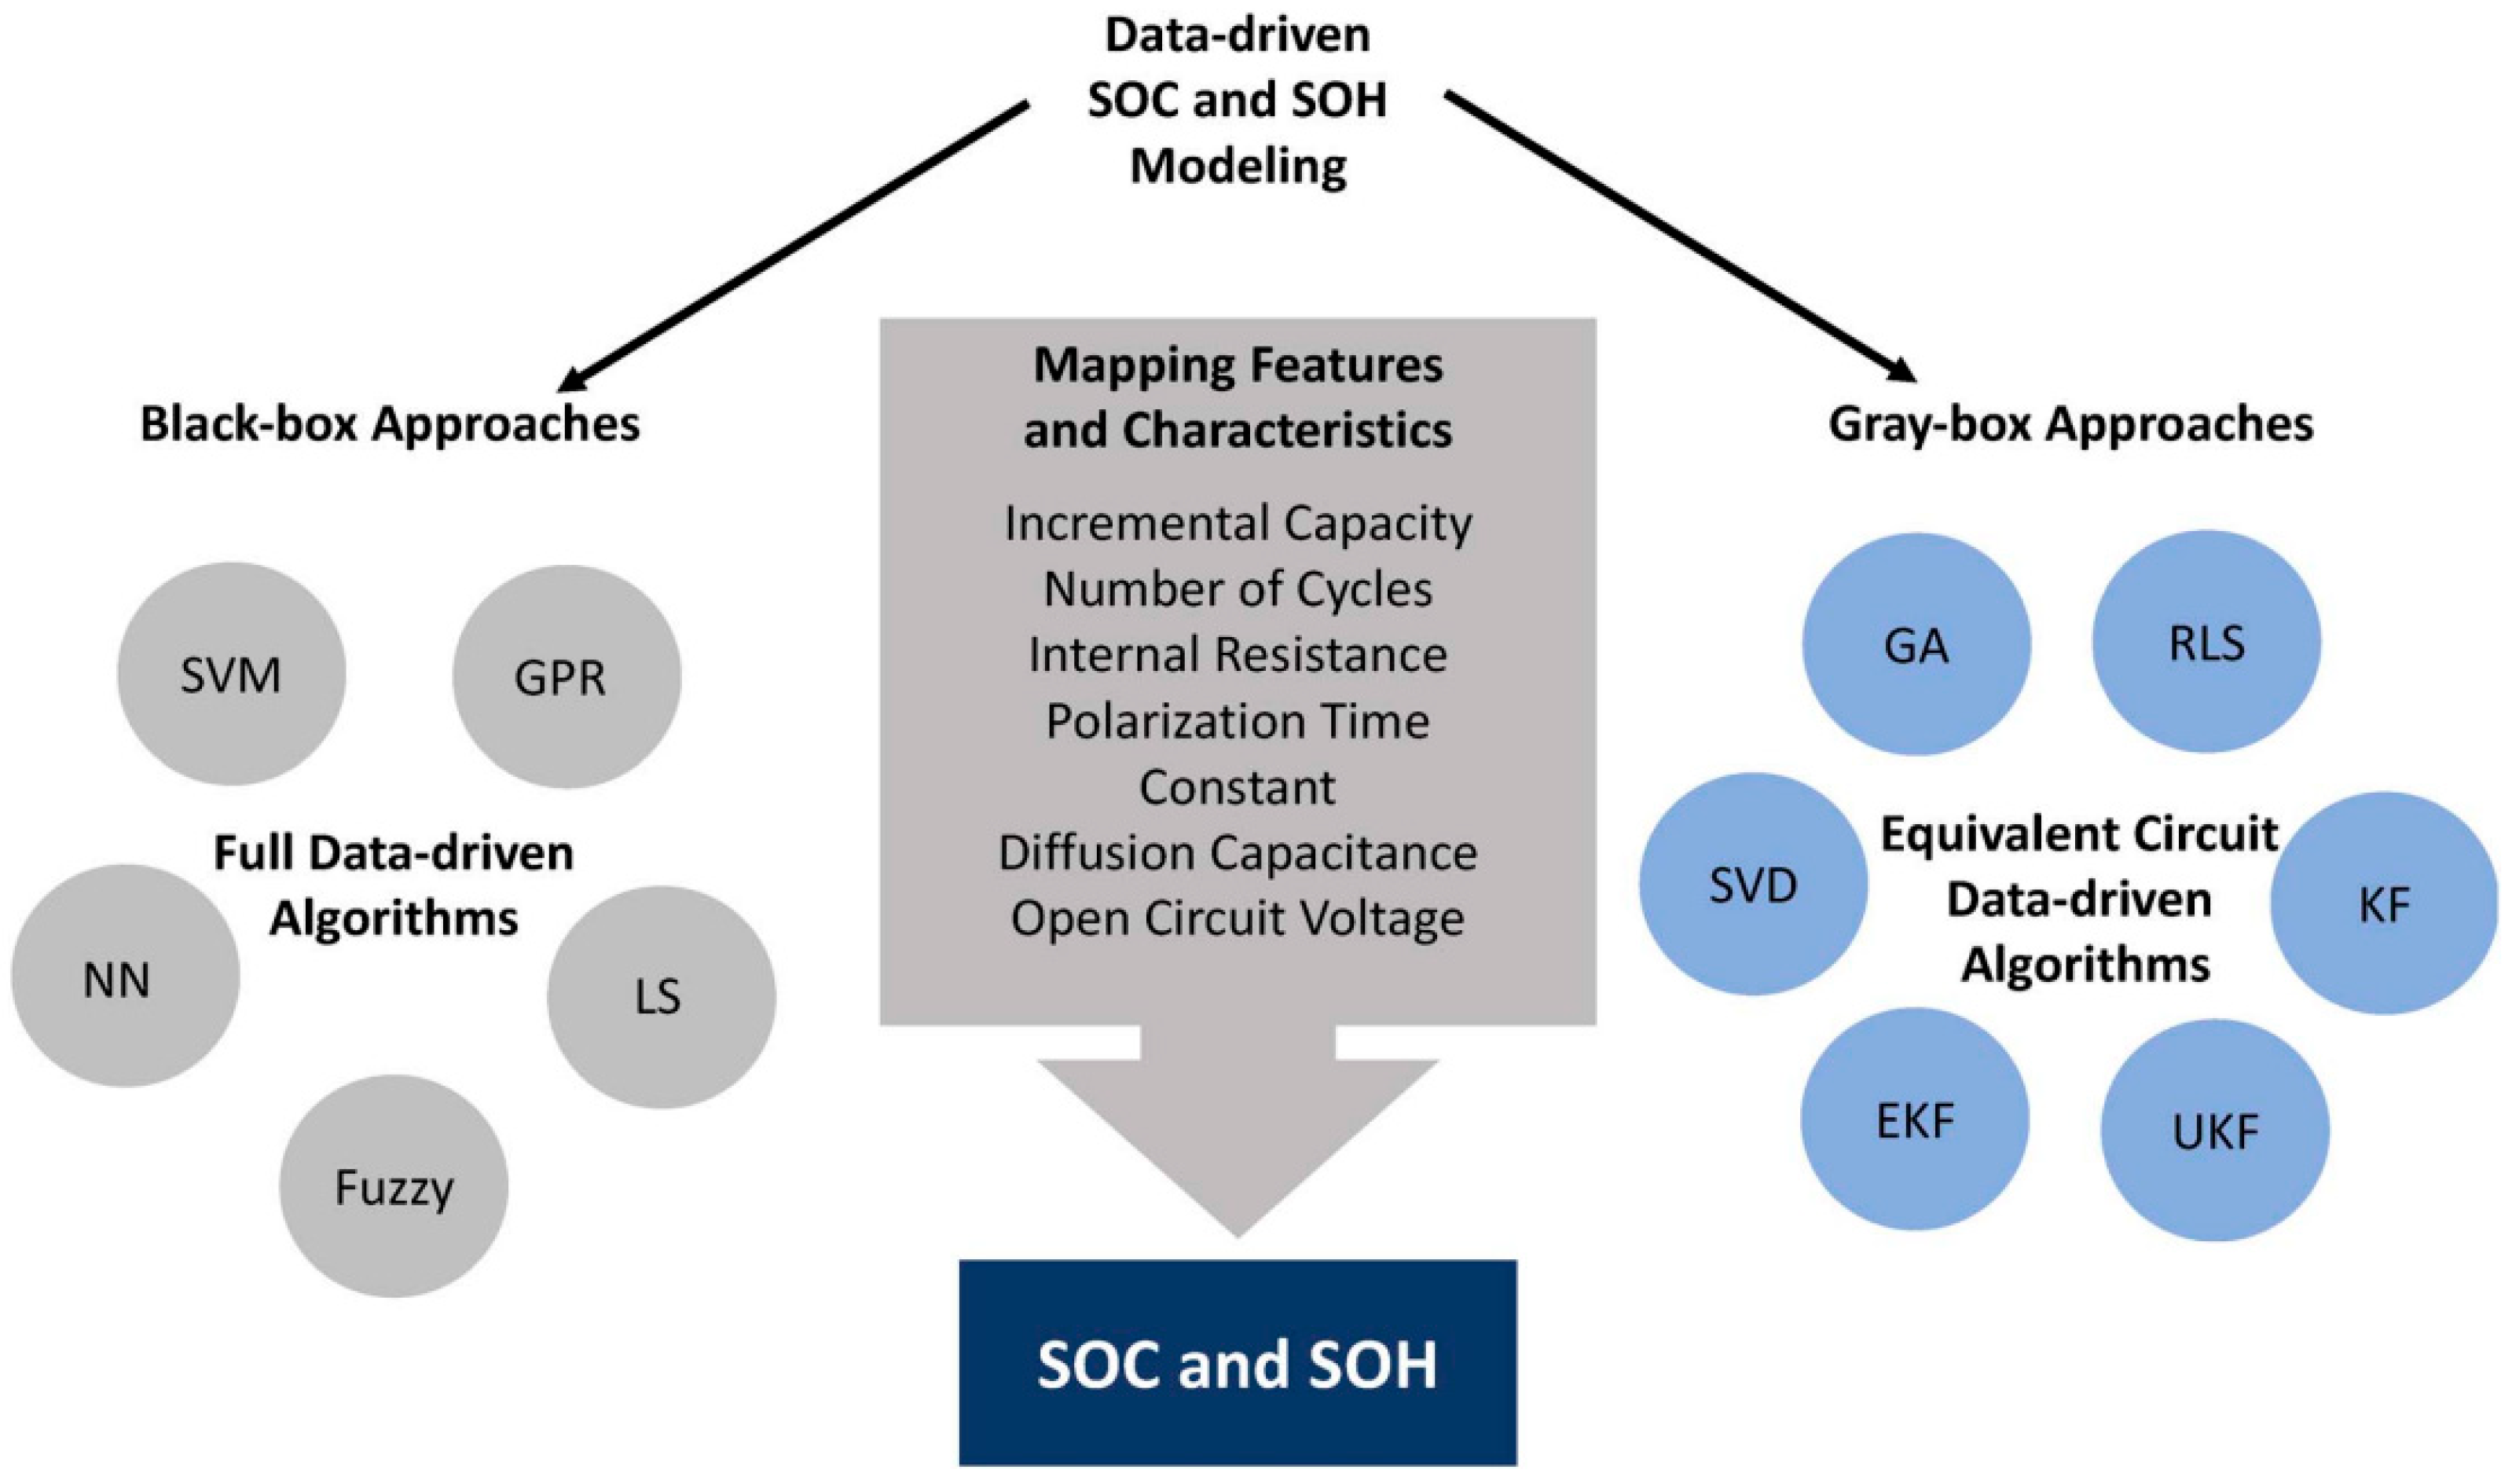
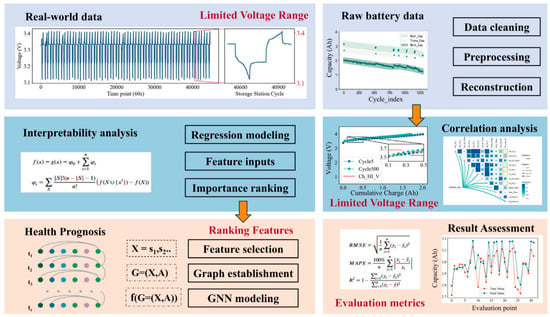
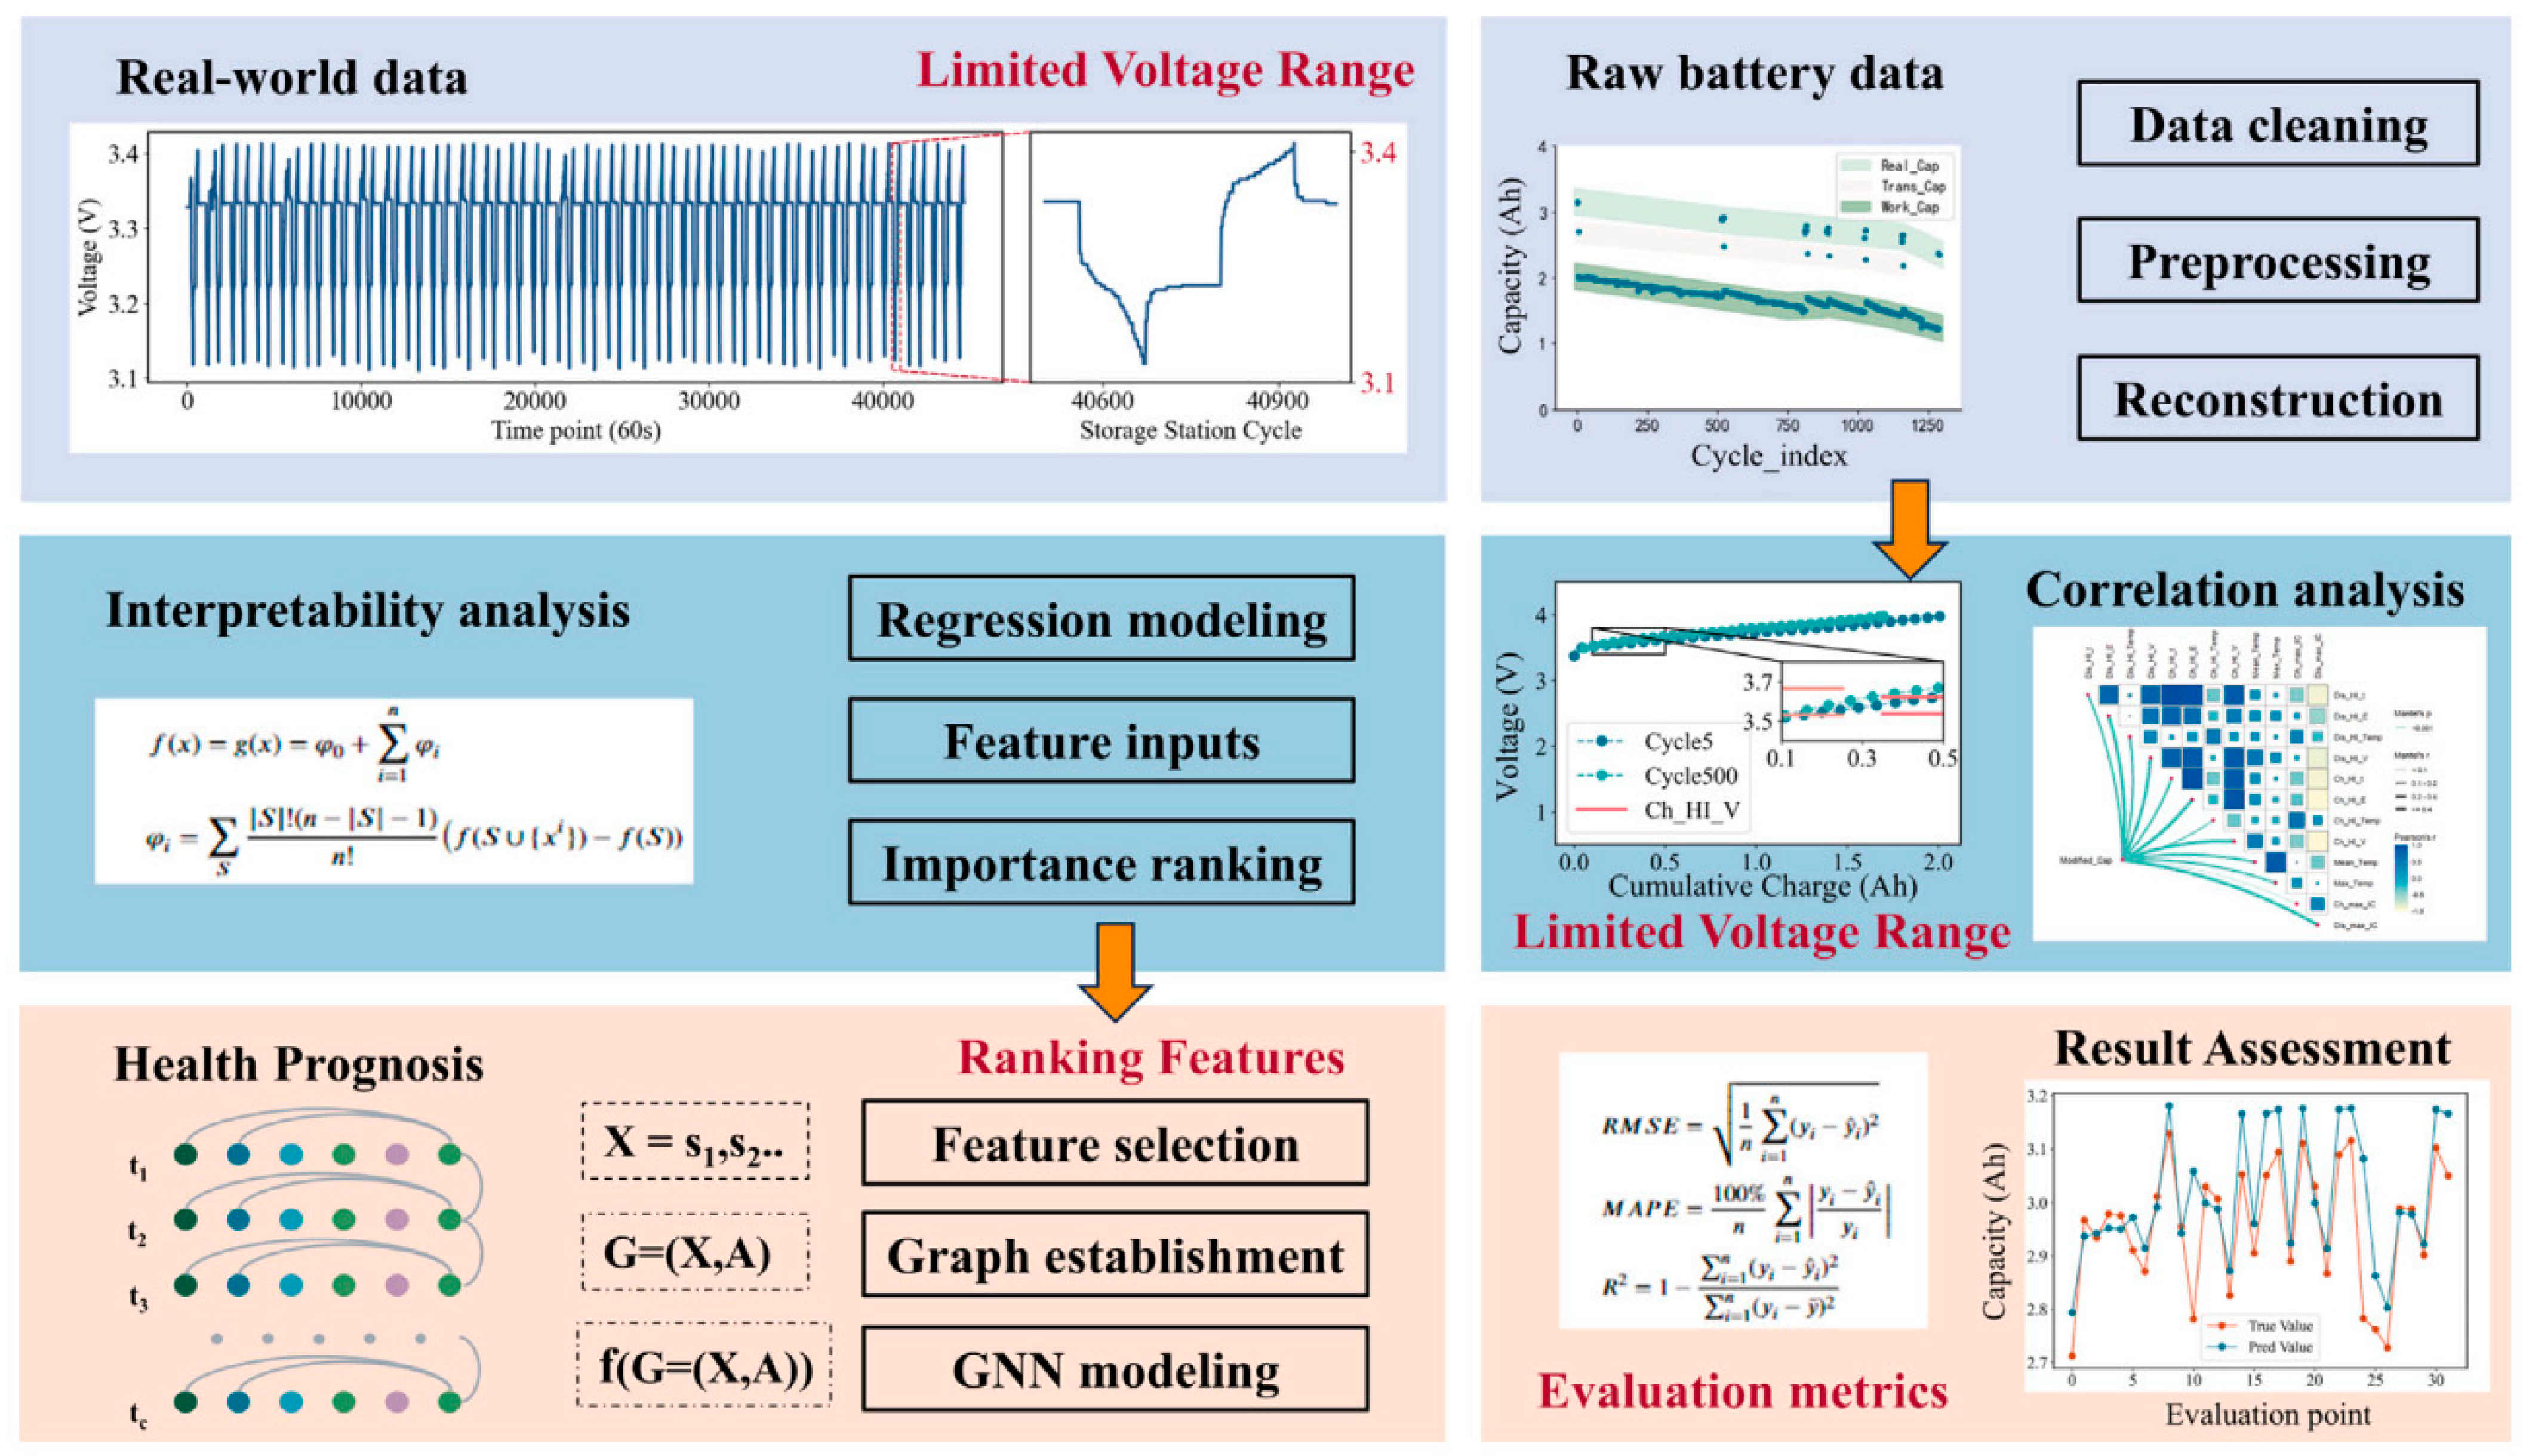
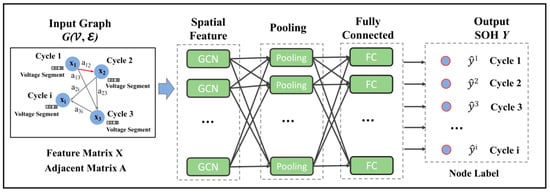
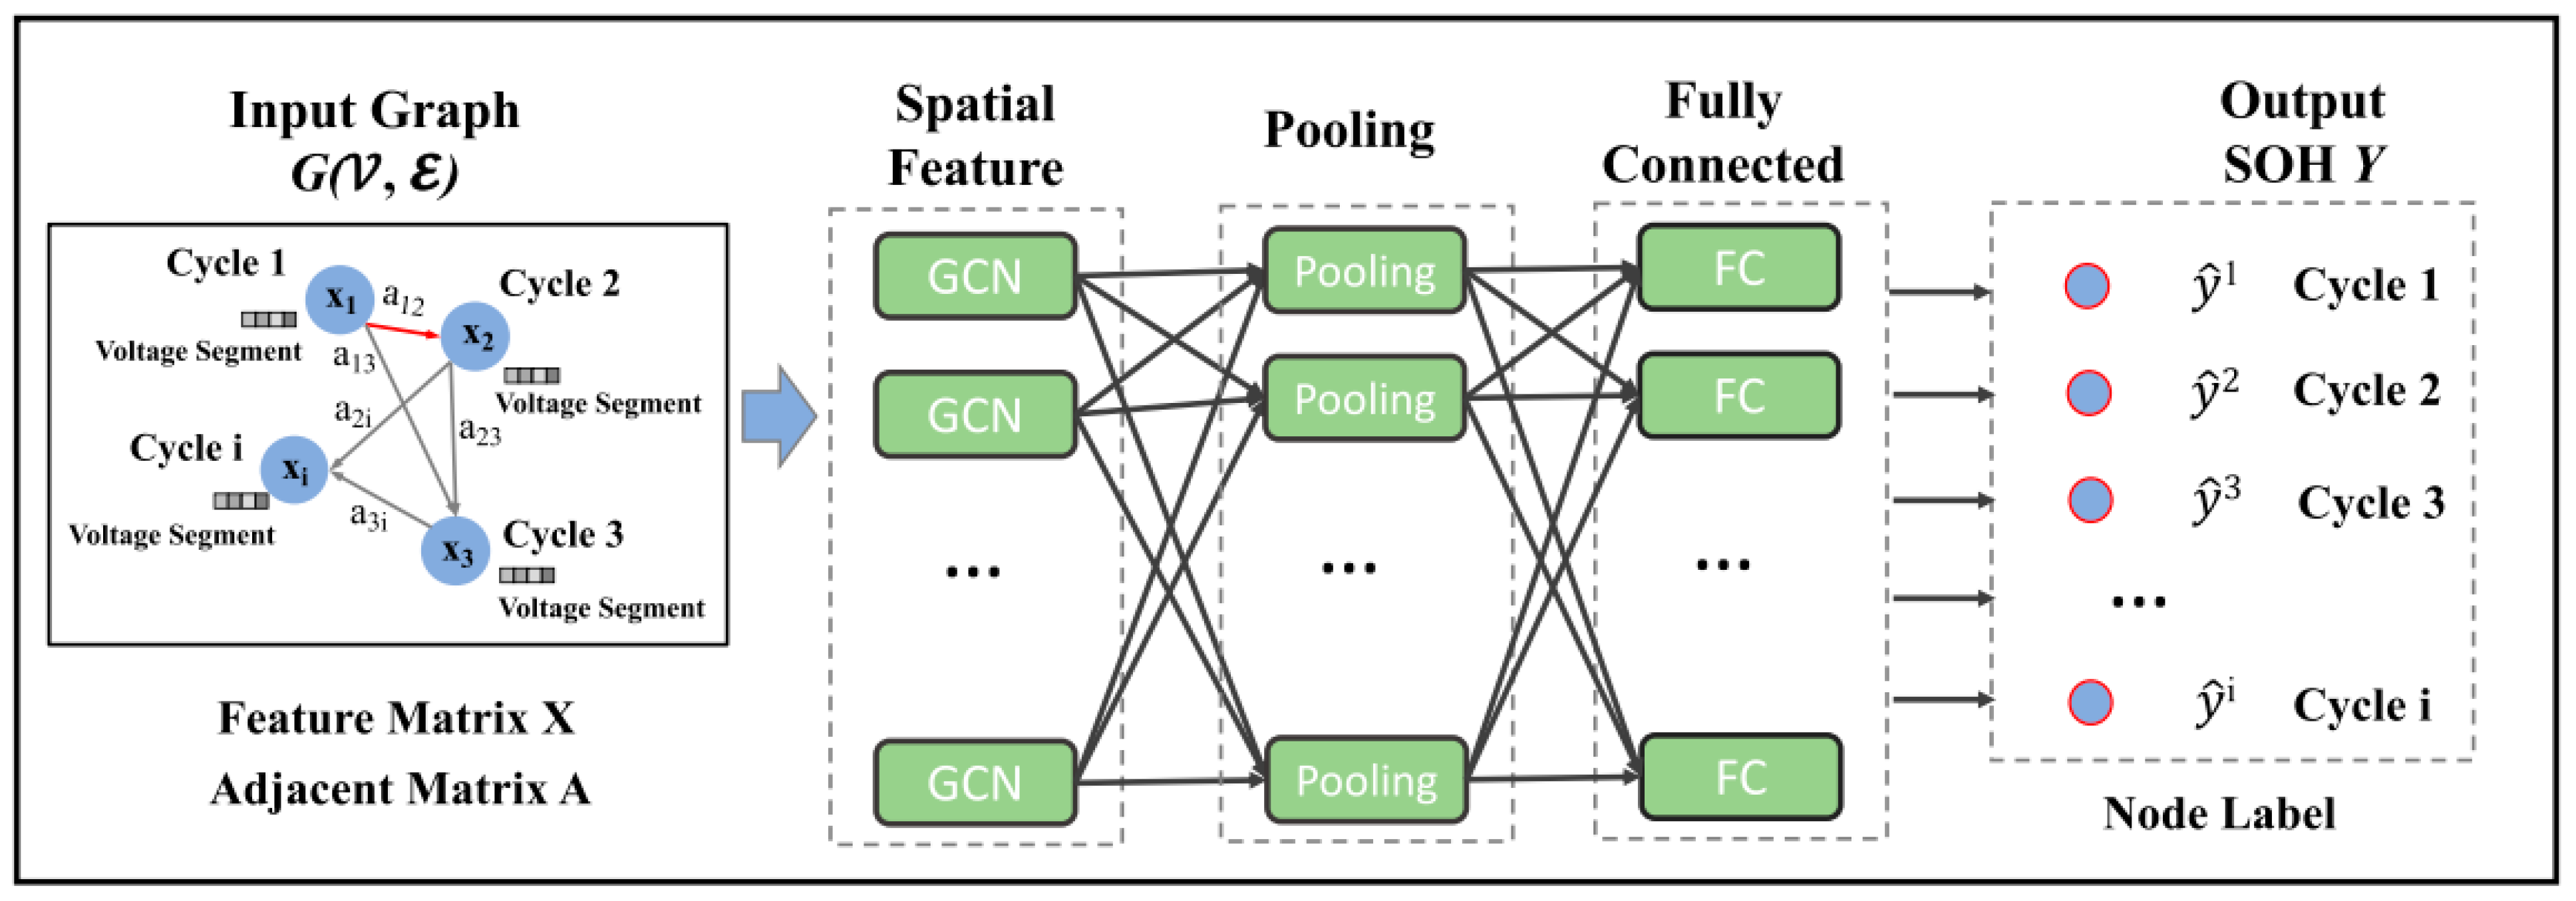
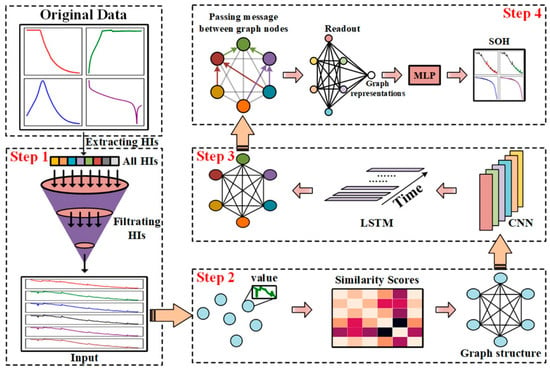
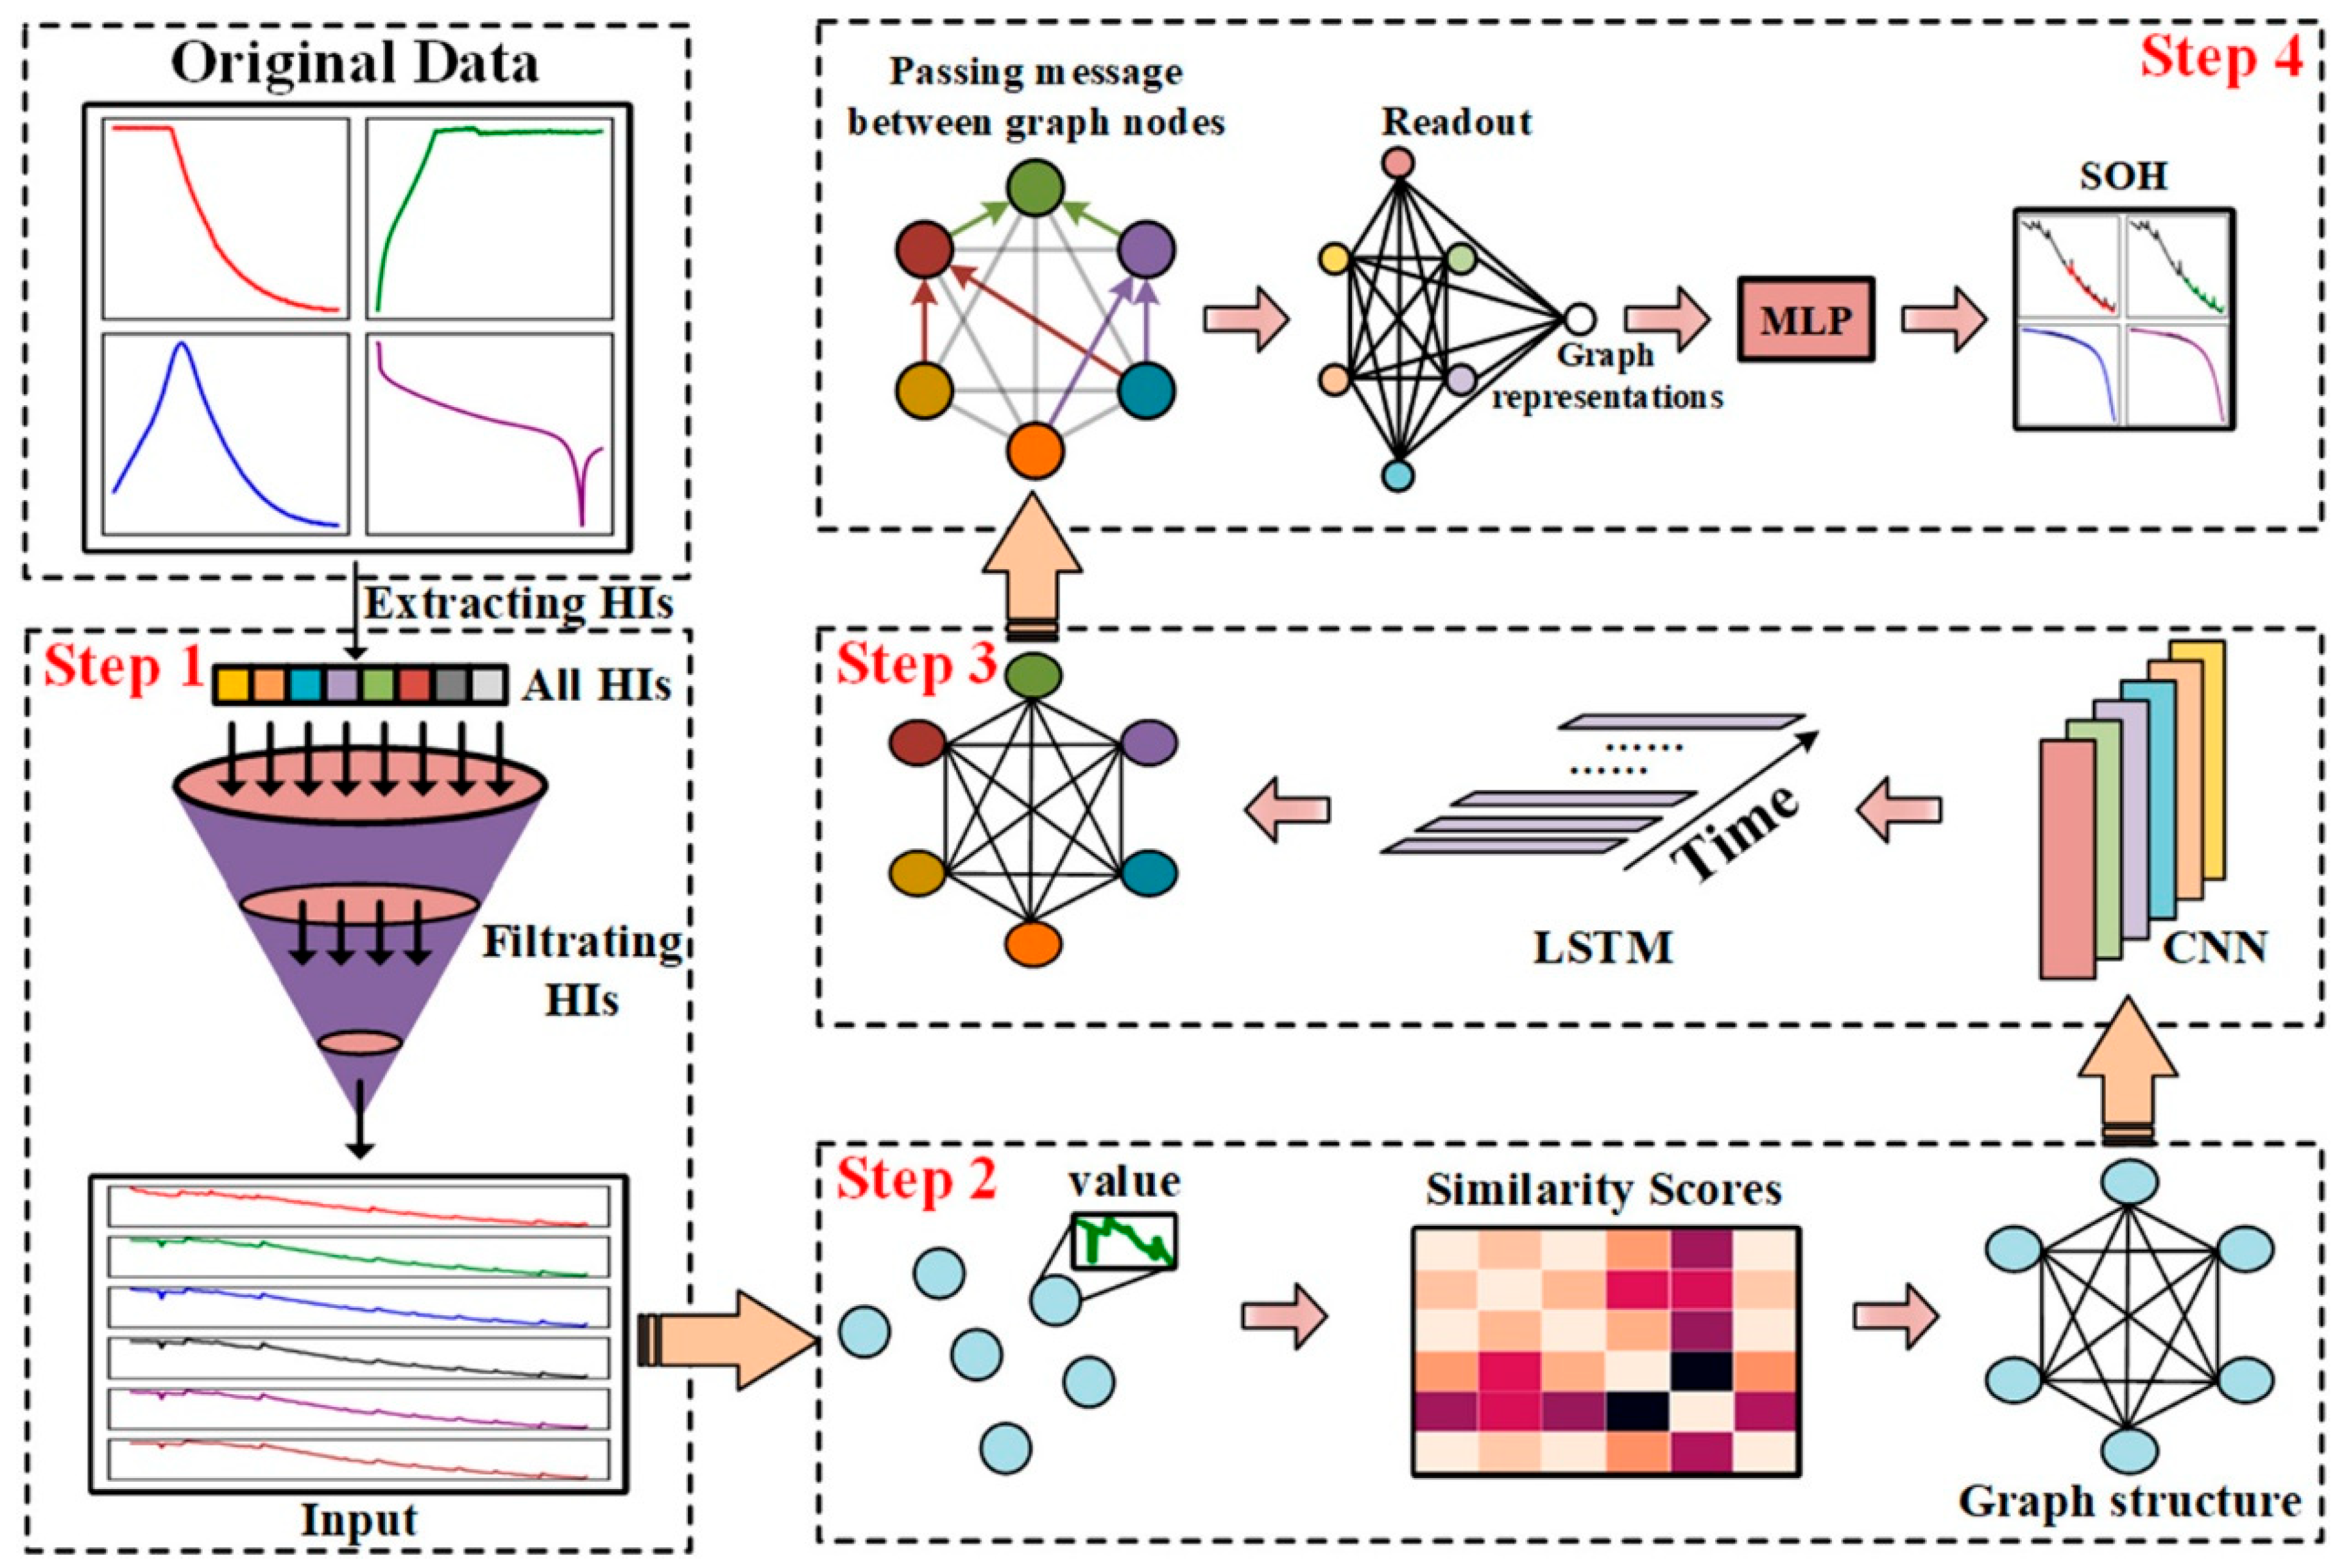
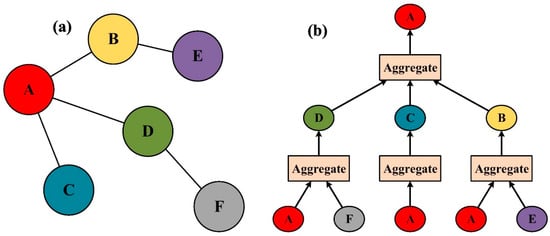
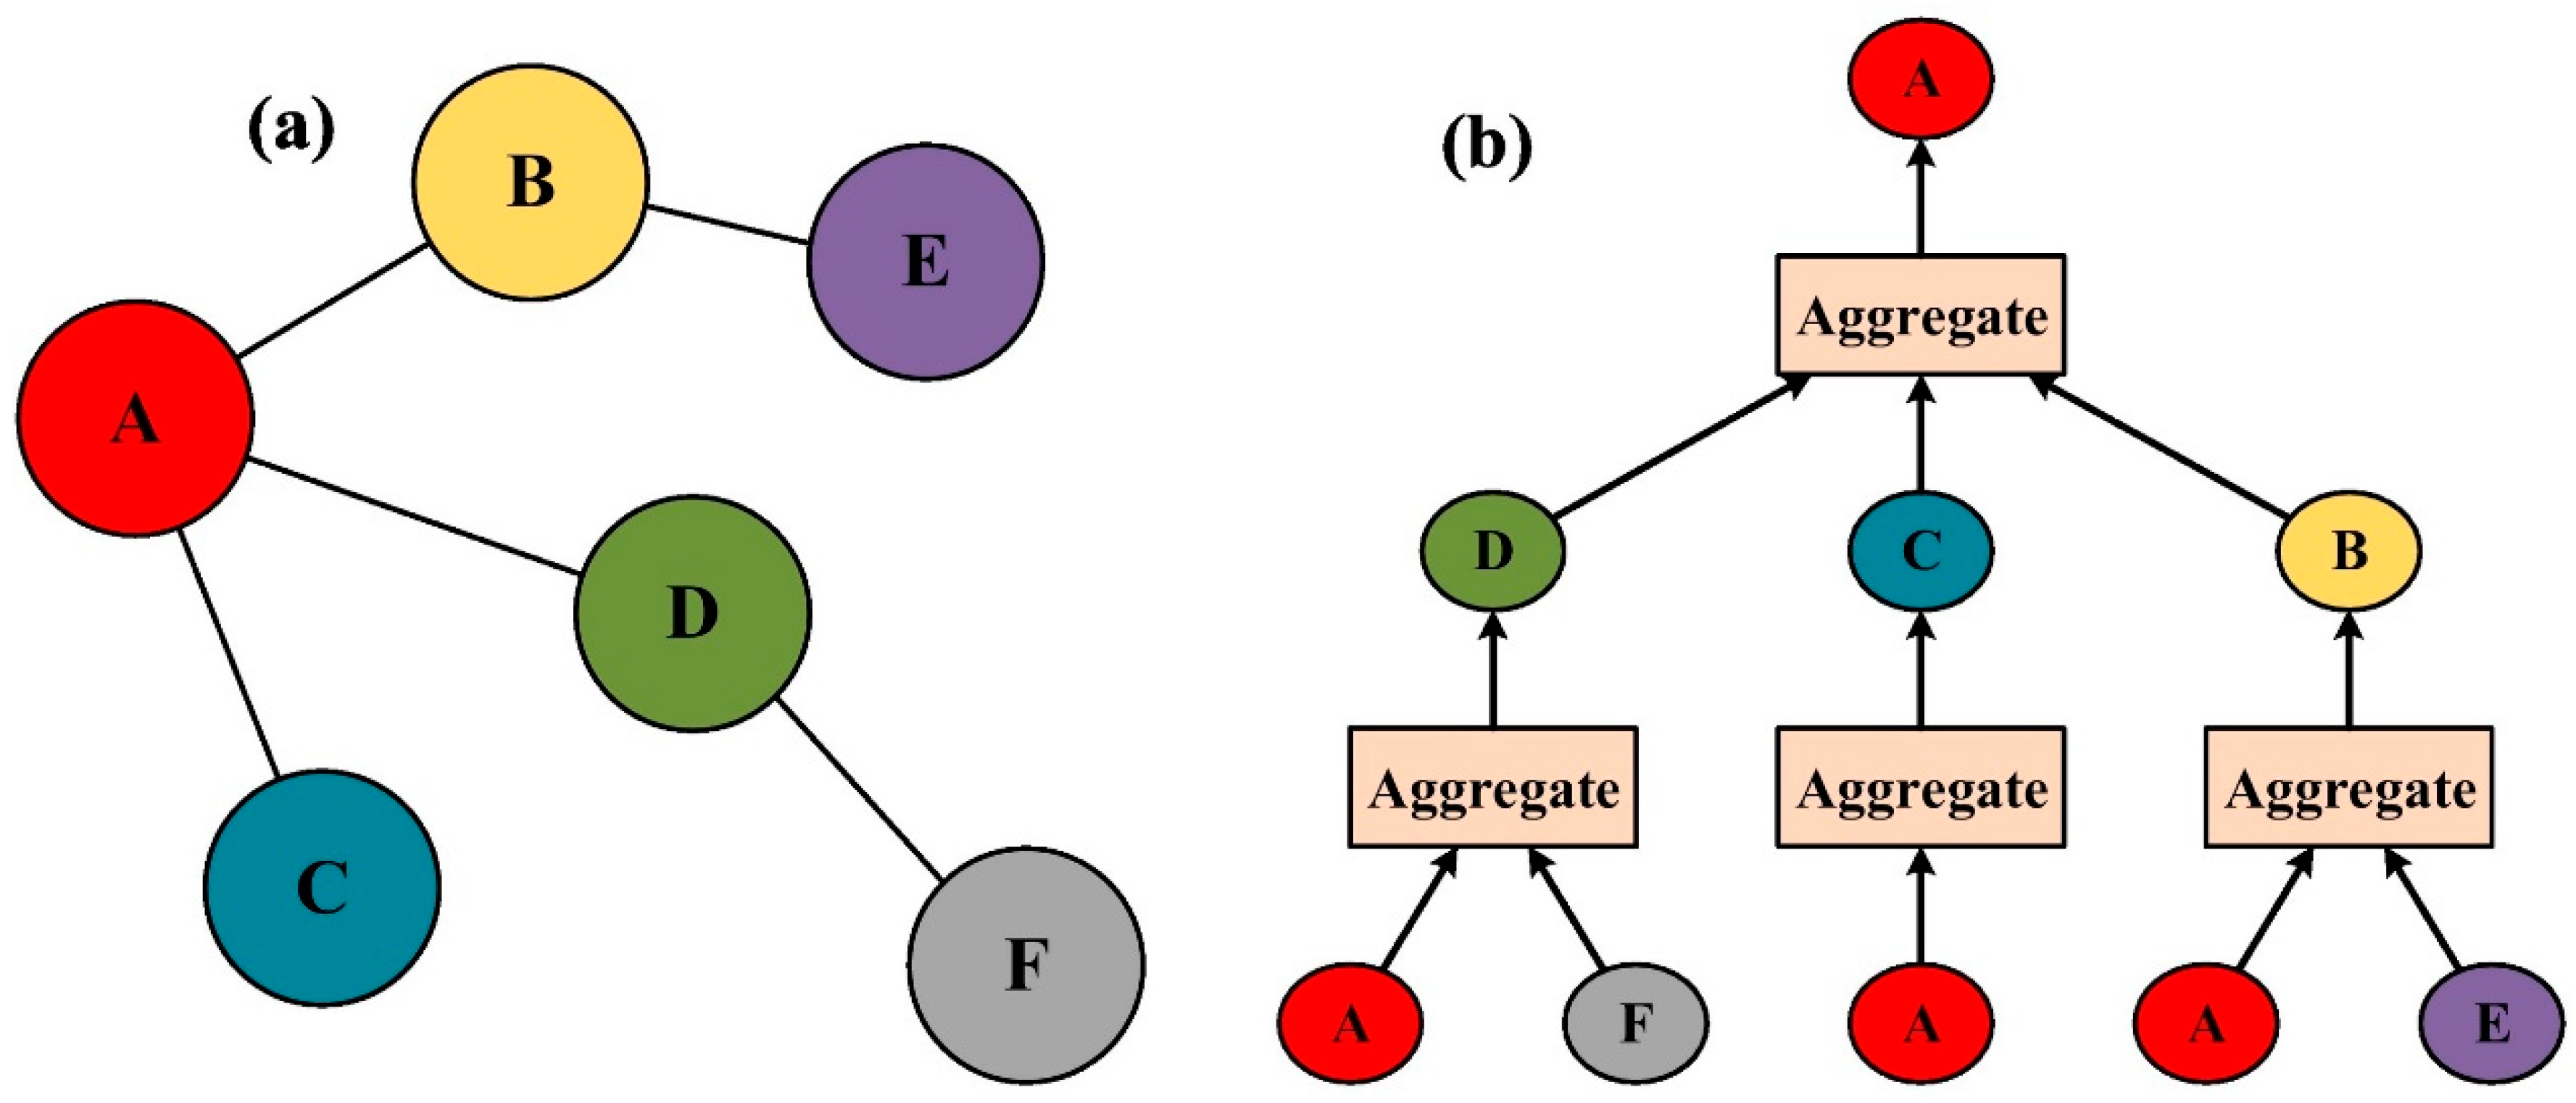
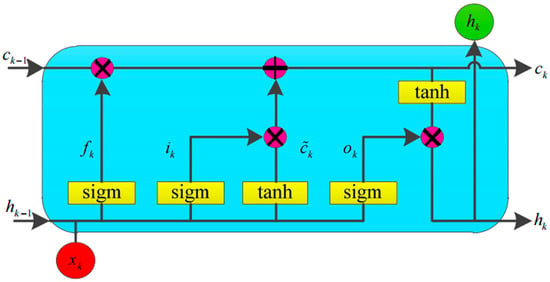
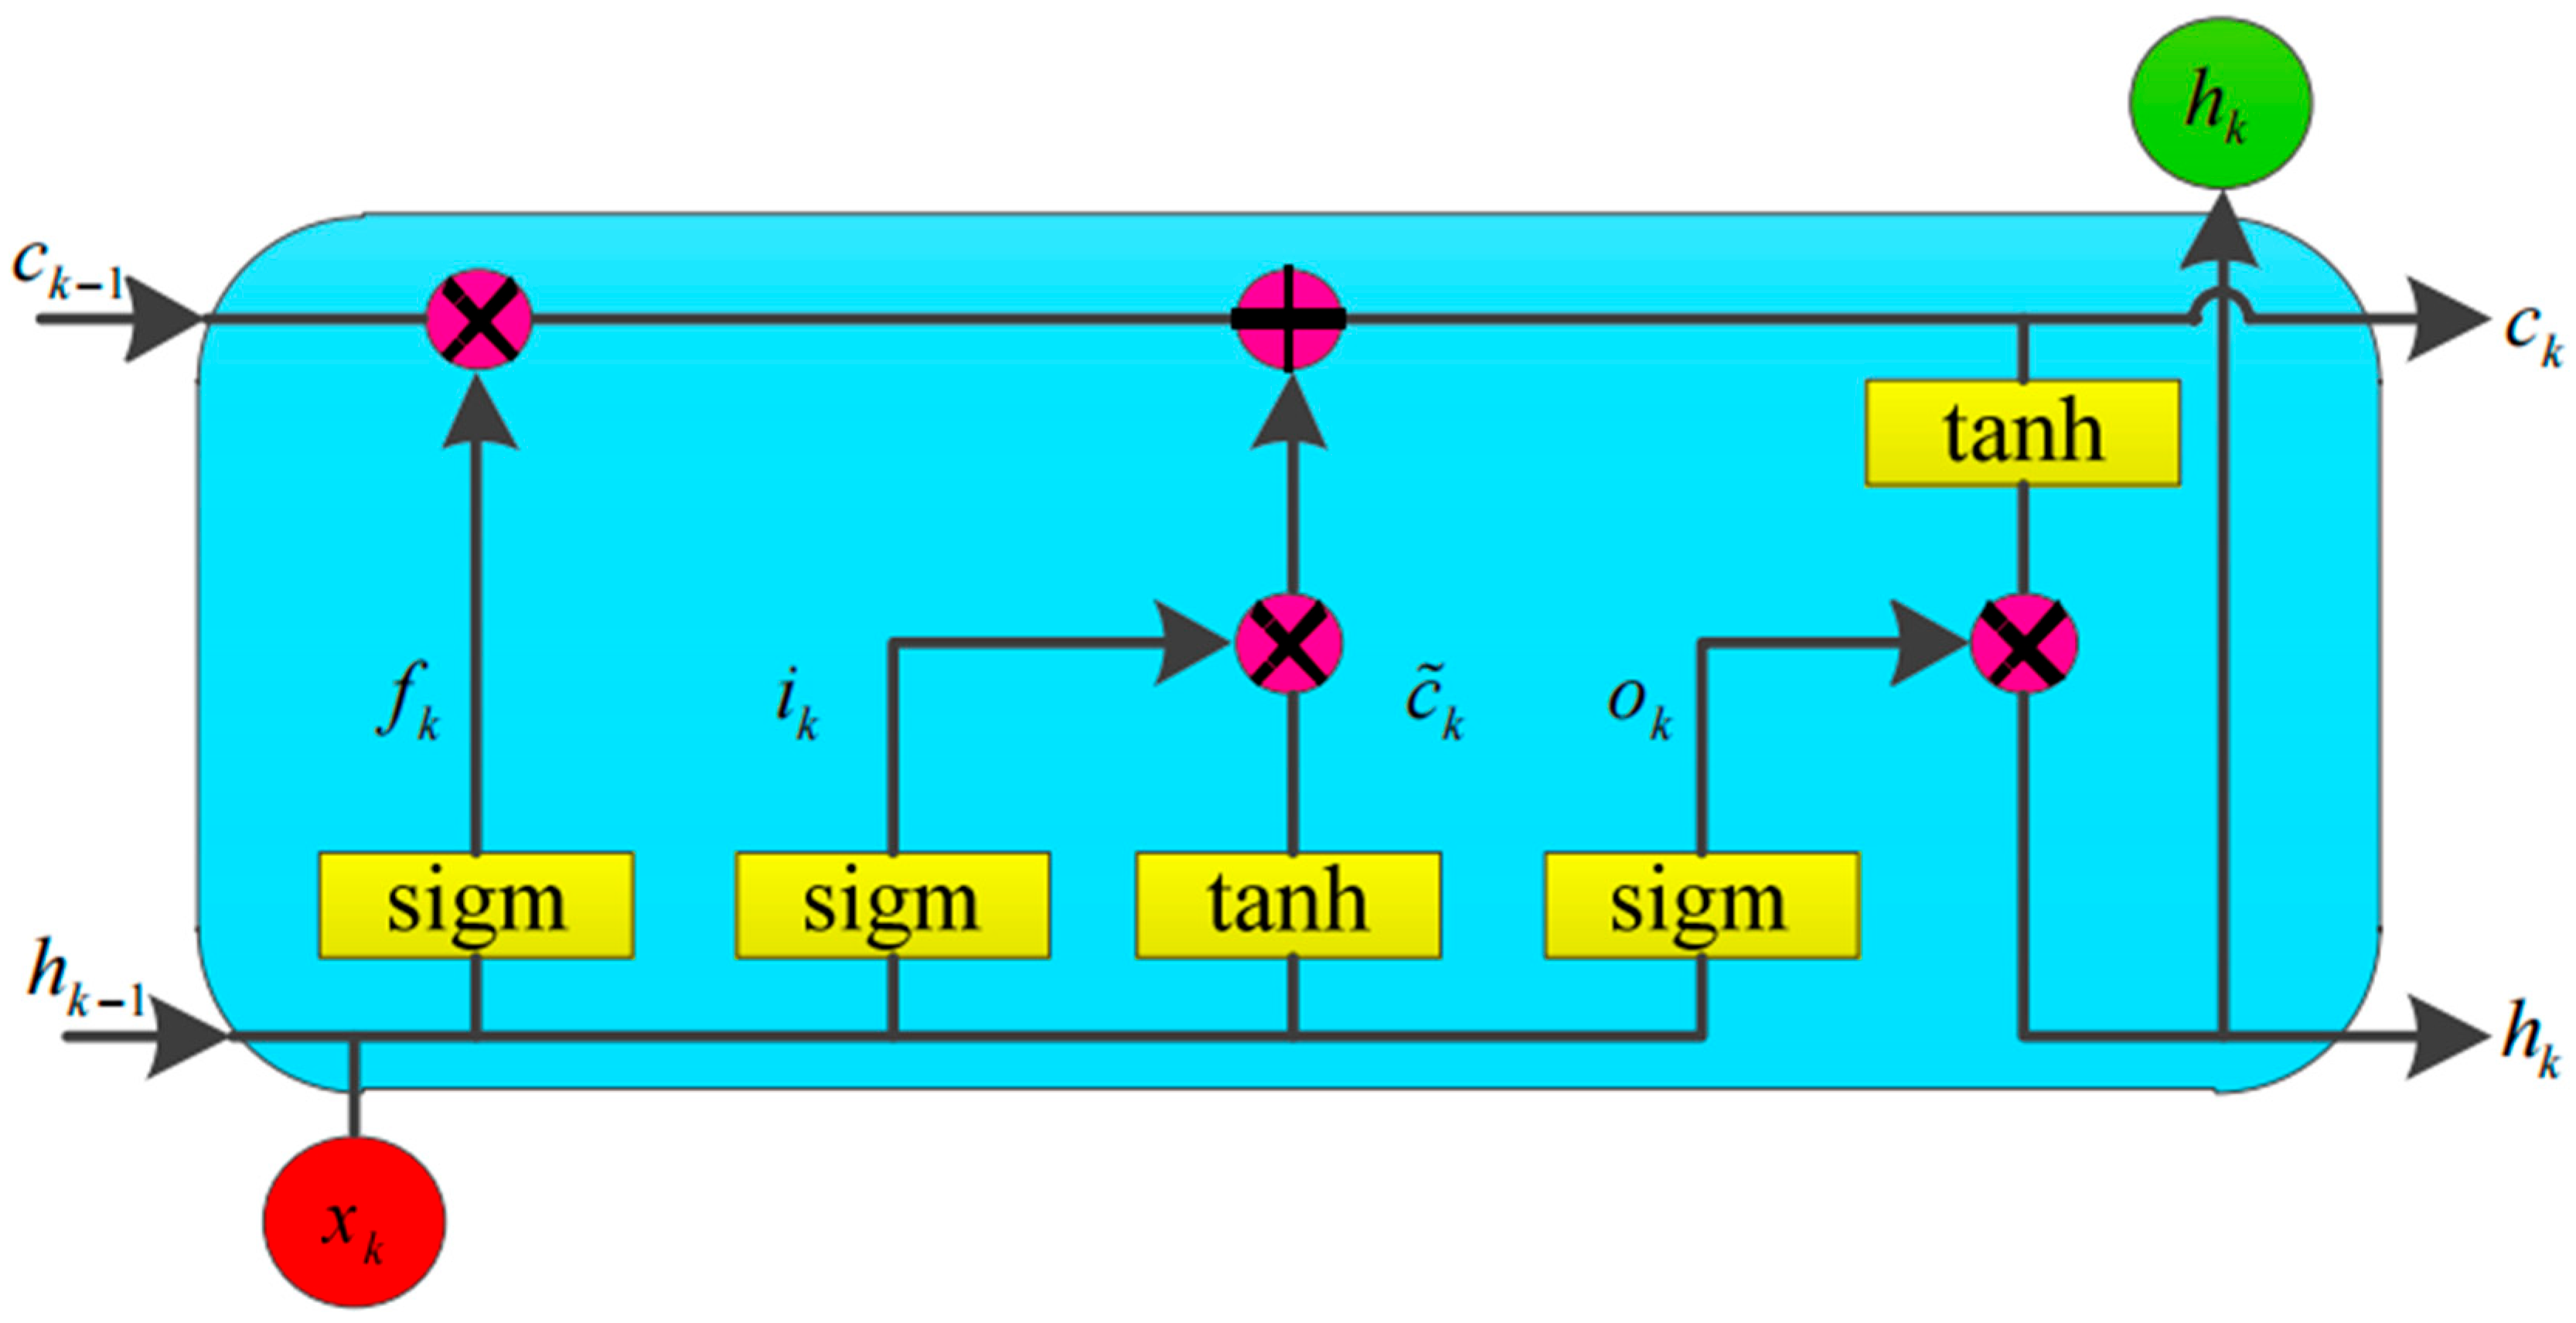
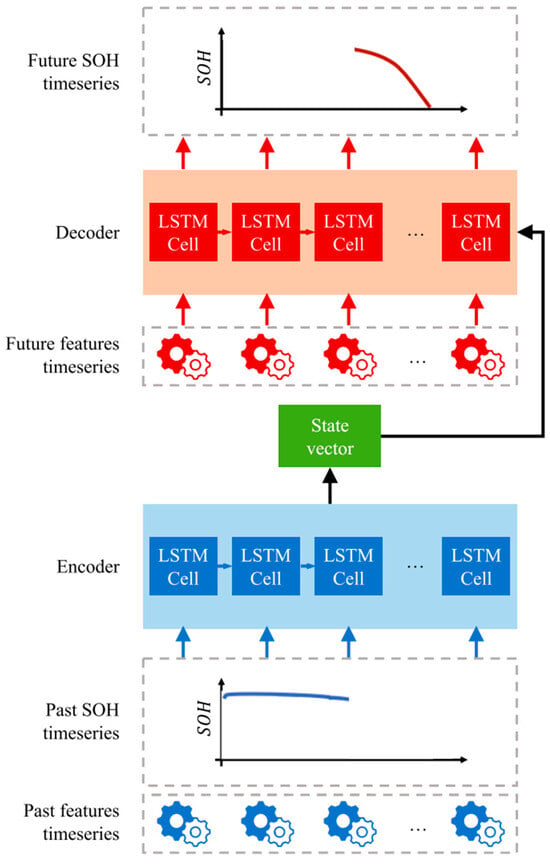
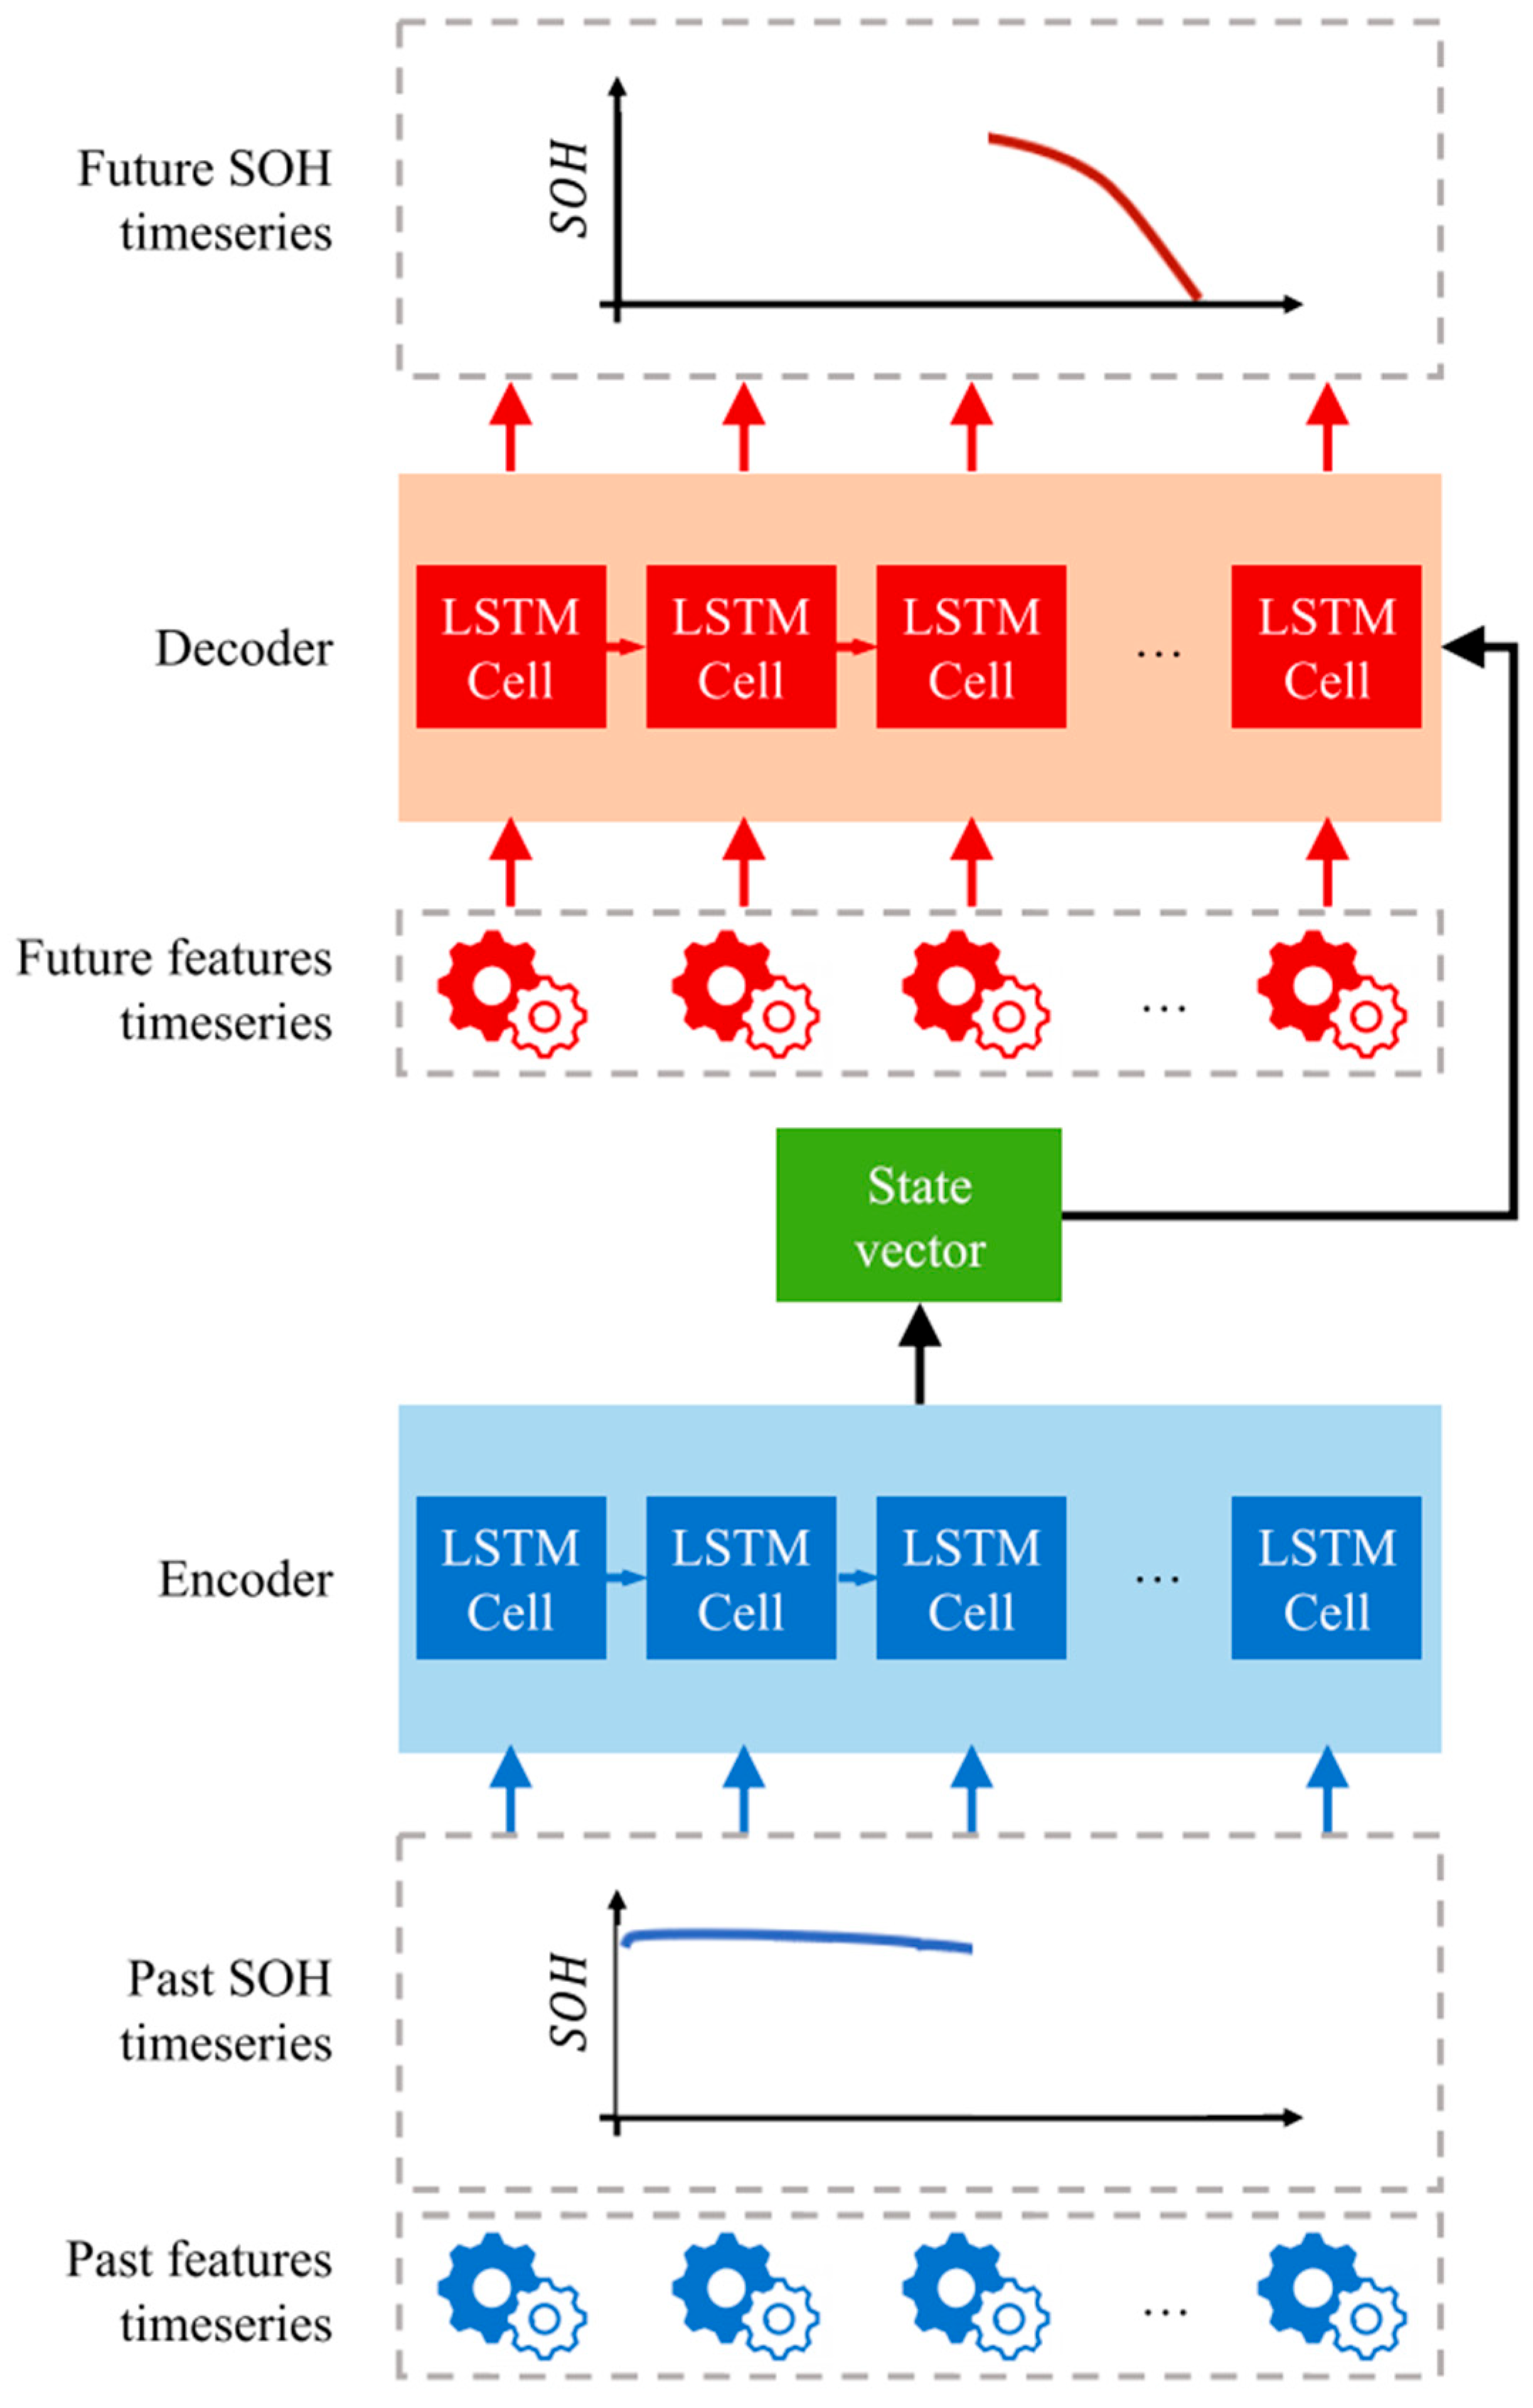
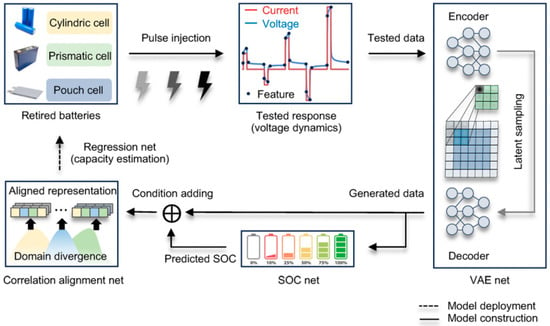
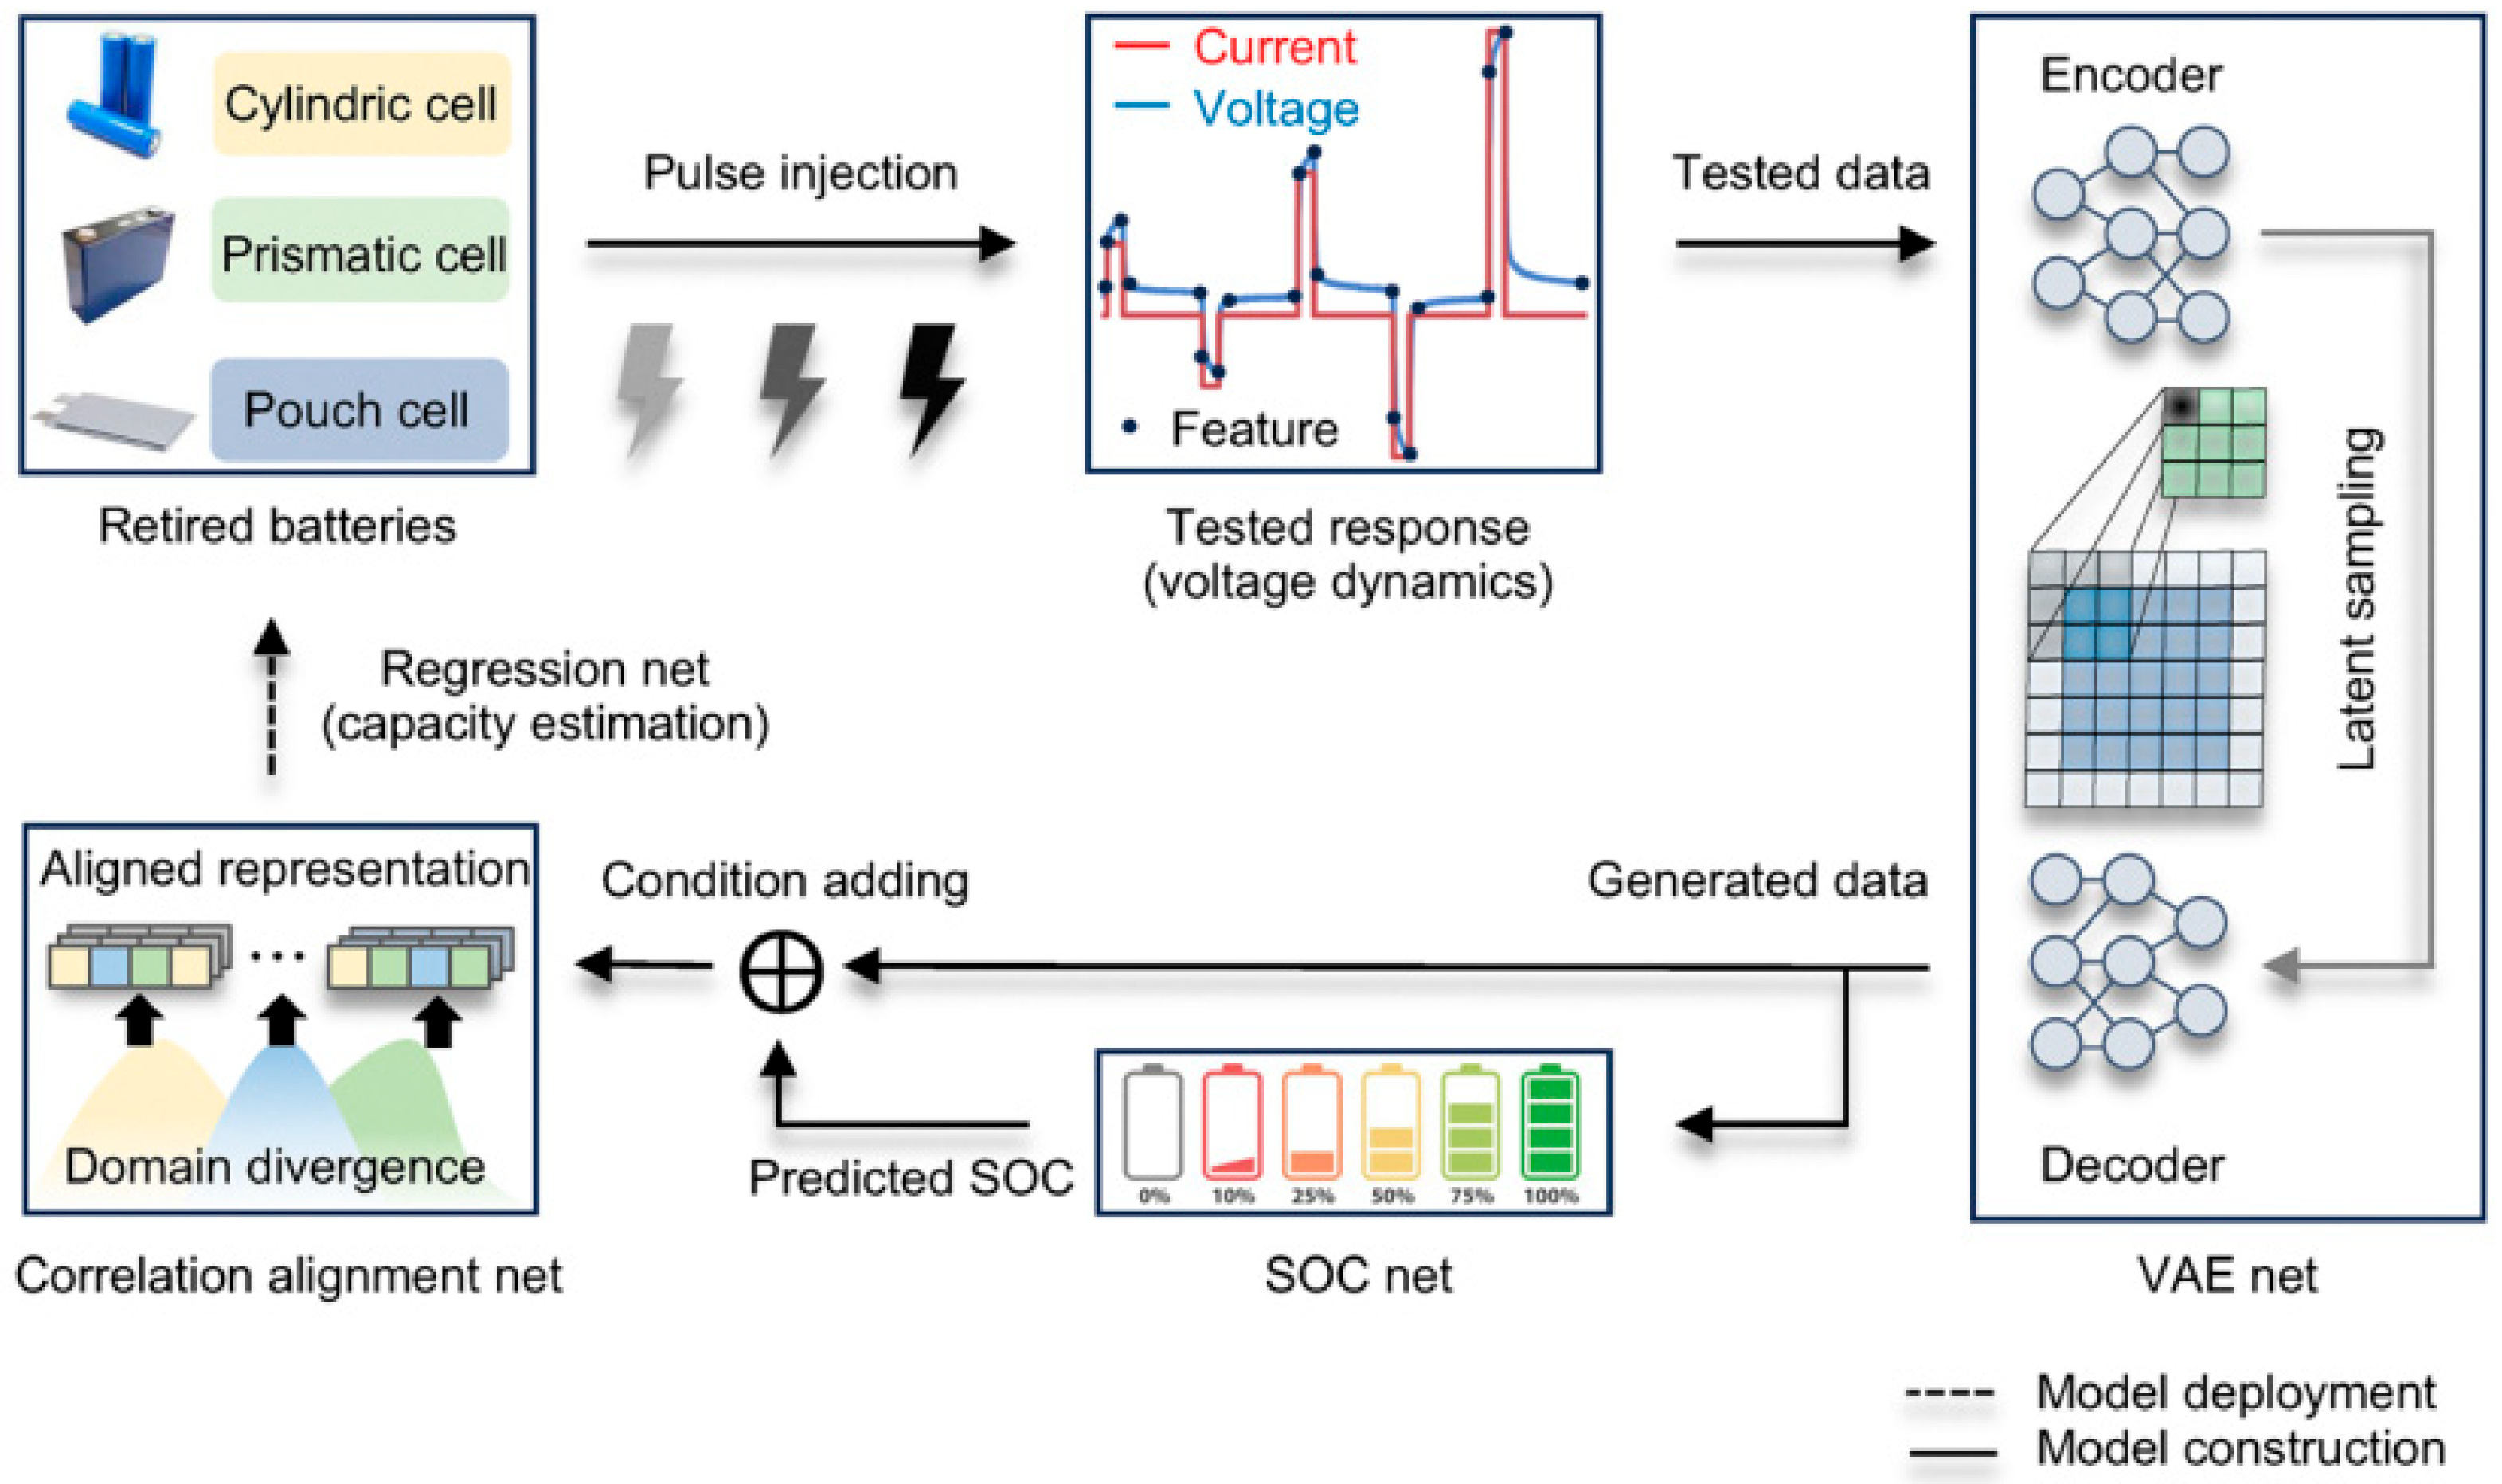
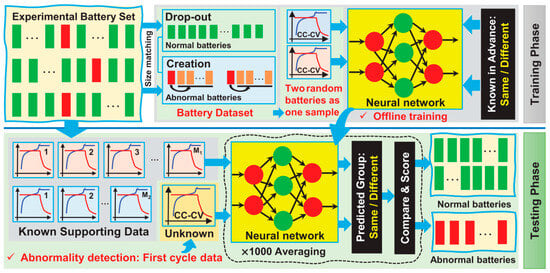
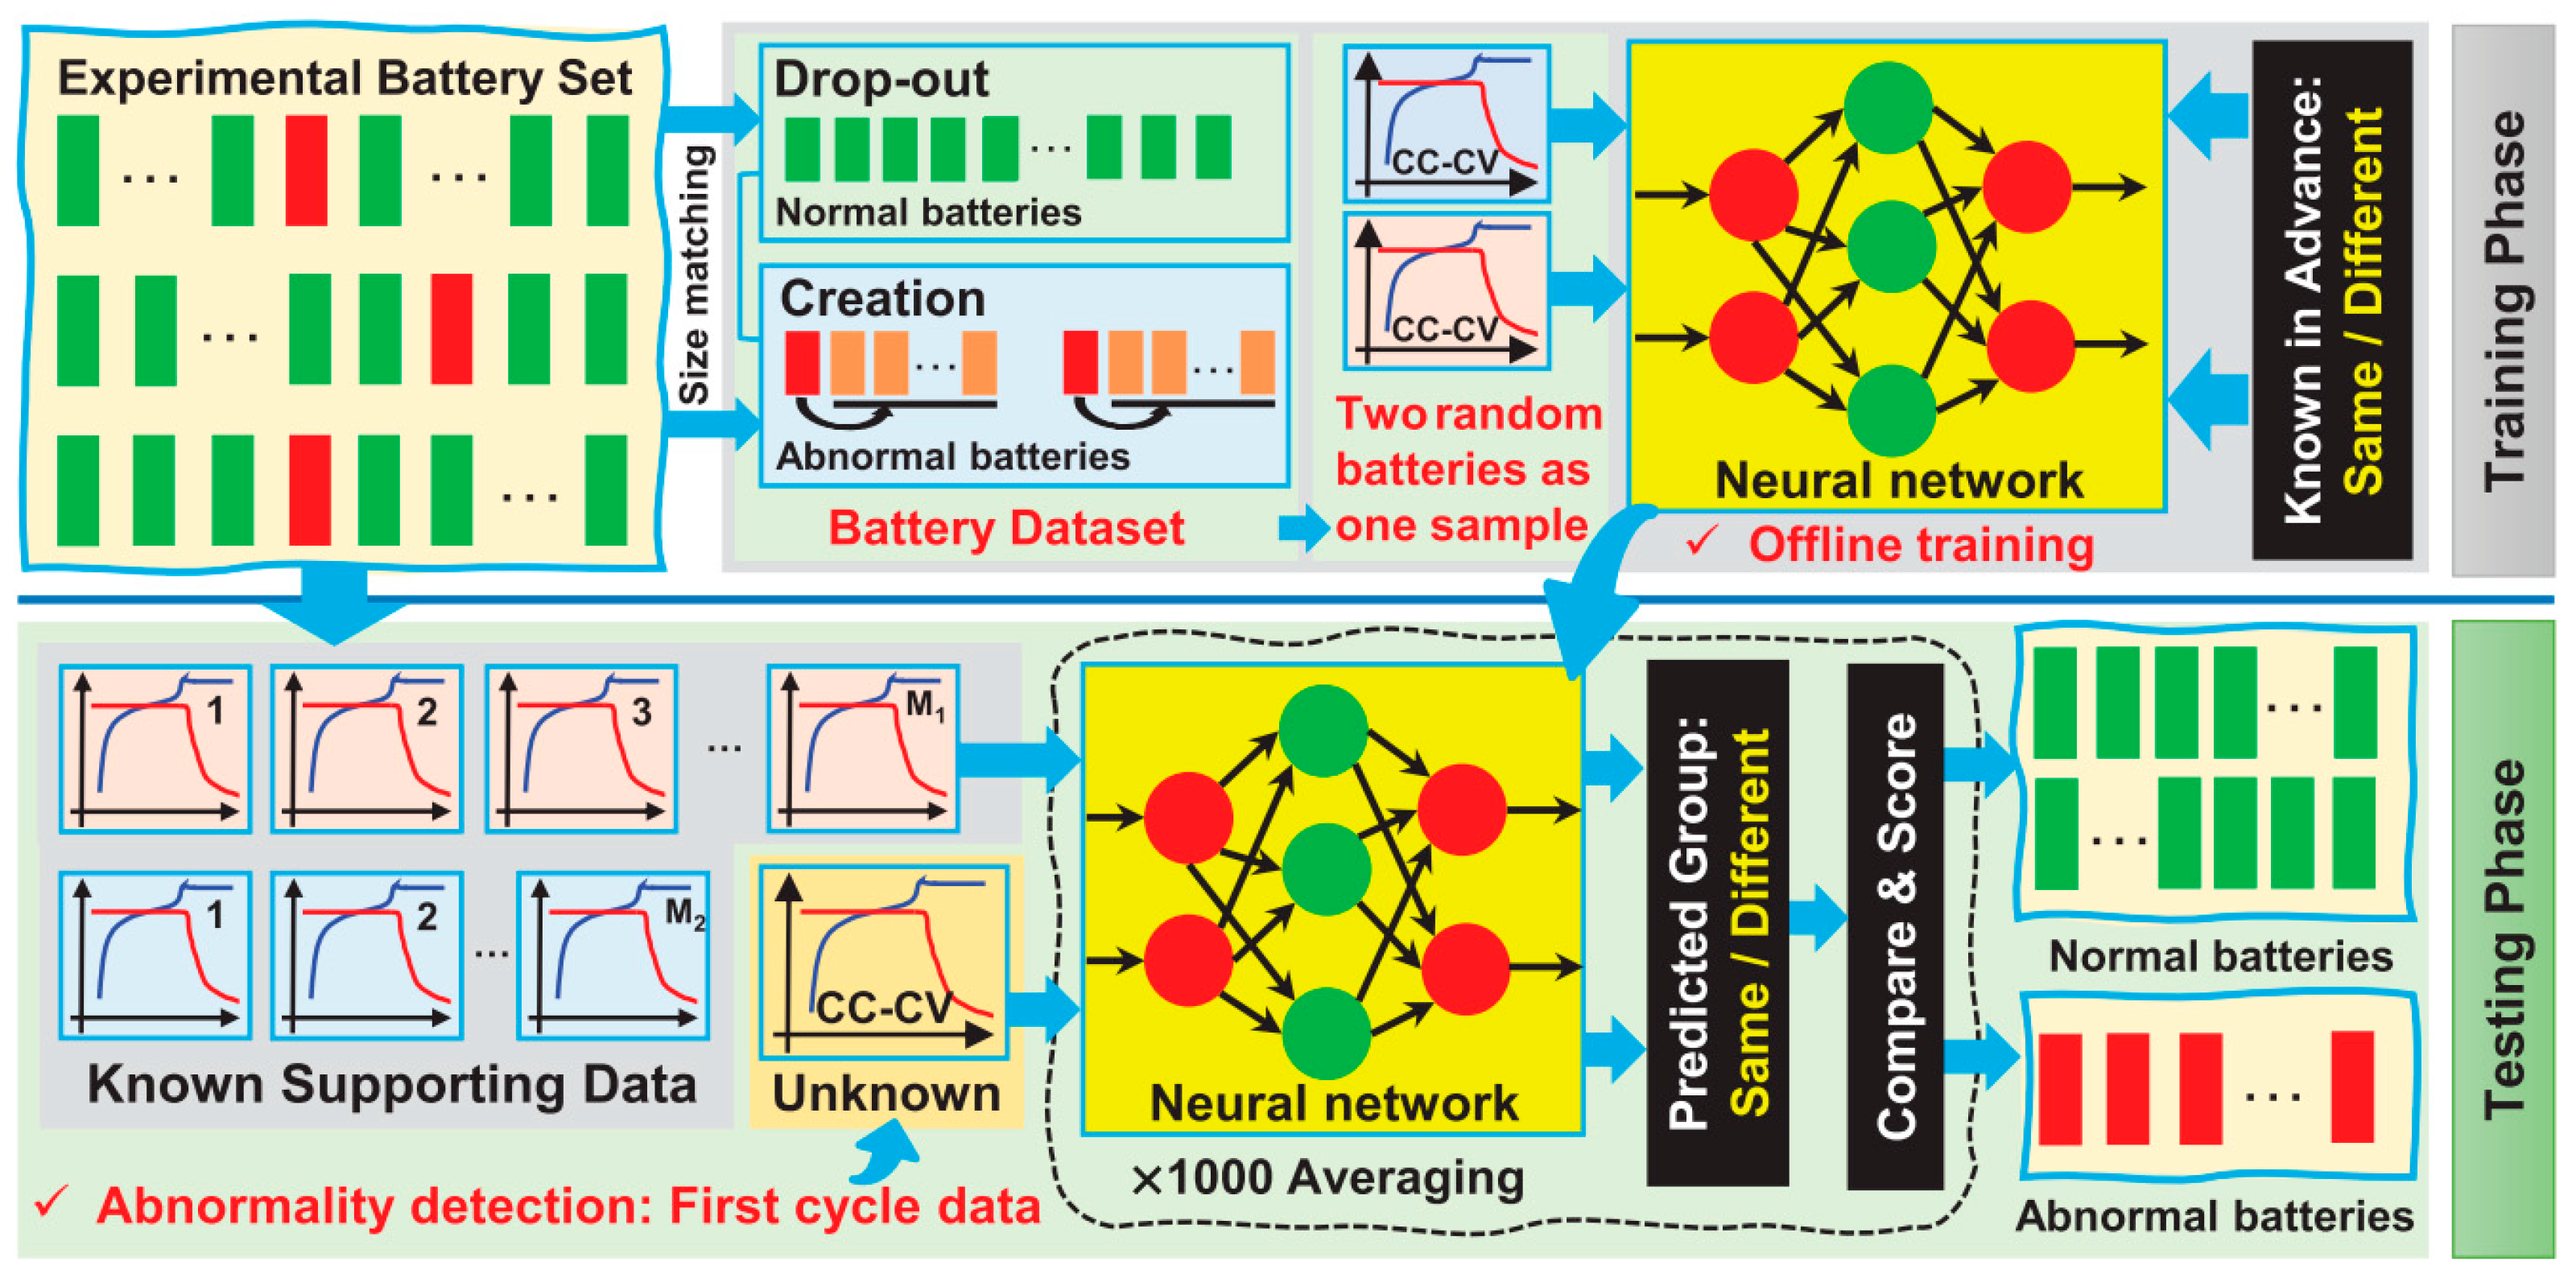
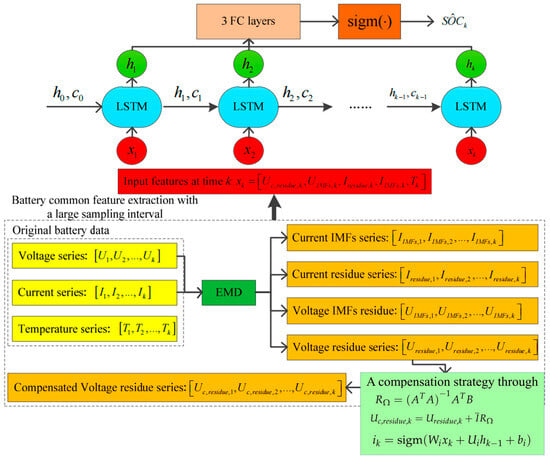
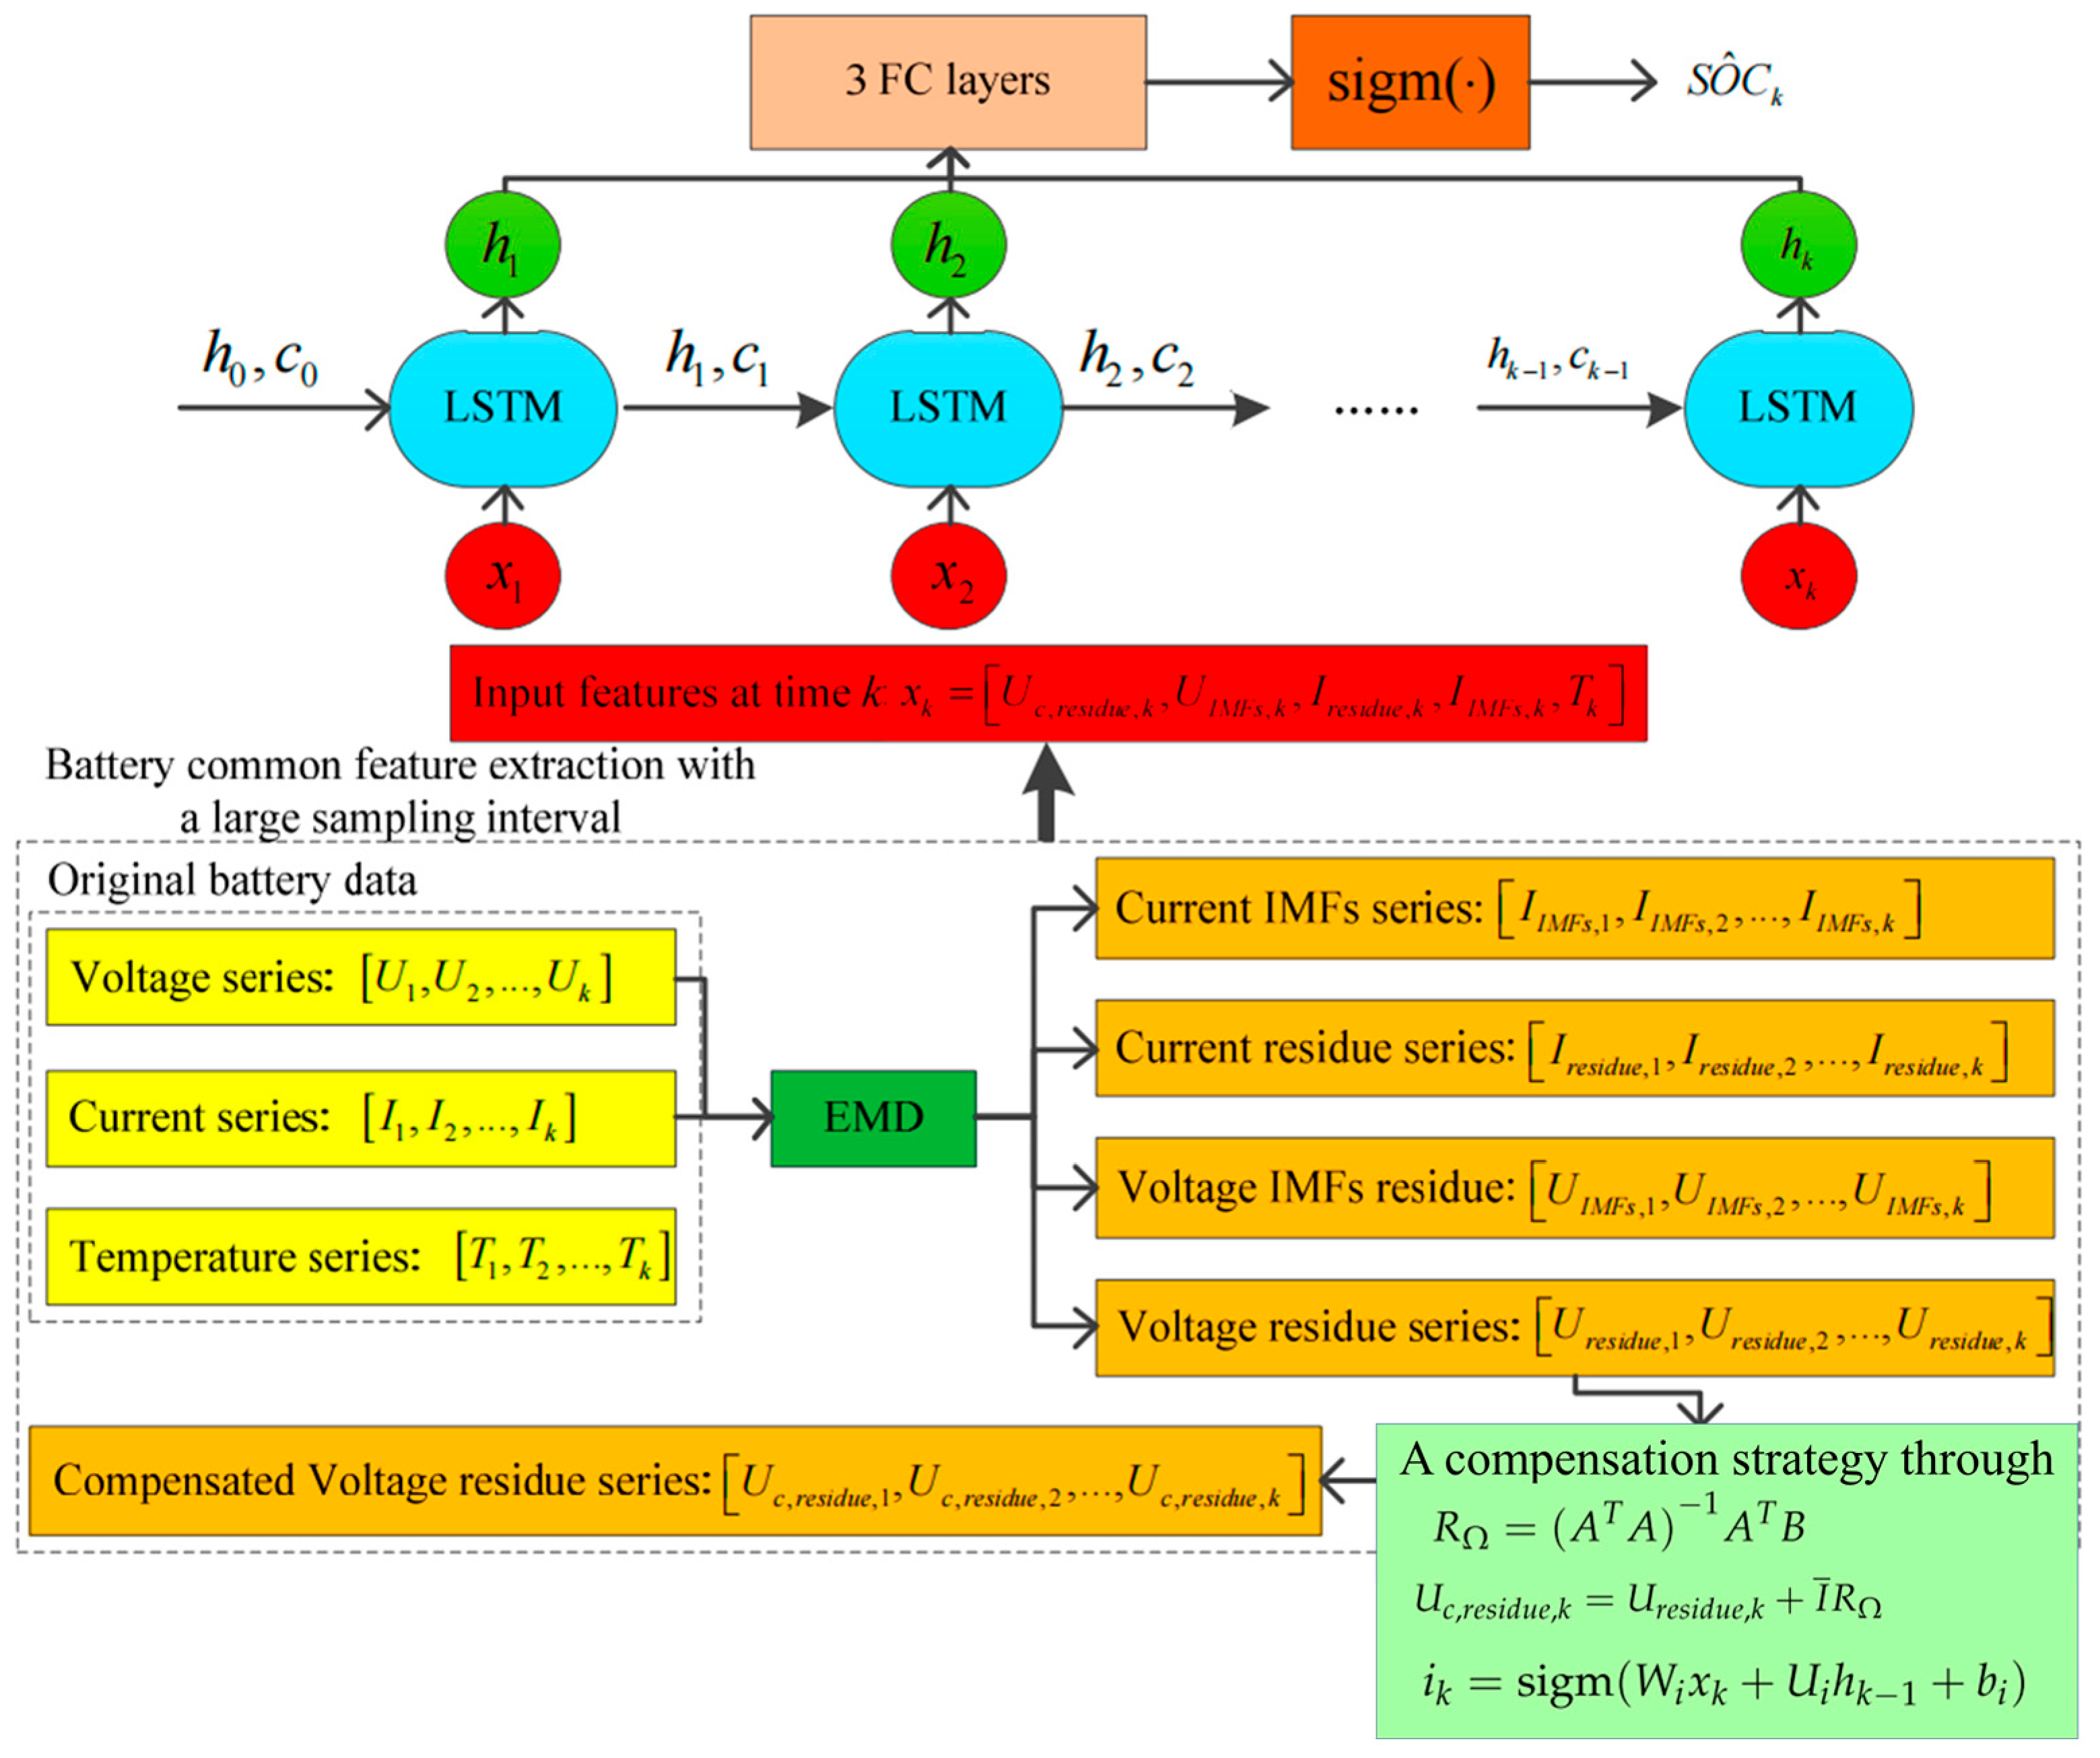

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.