


Abstract
The advantages of hybrid models for time series forecasting have received significant attention, and several studies focus on and test their application in the seakeeping of ship motions. A hybrid model integrating an LSTM encoder and Transformer decoder (LT) is introduced to overcome the limitation of individual LSTM and Transformer: initially, the seakeeping response of the KCS ship was simulated by ANSYS-AQWA considering the sea state 3 and 4 simultaneously and established a dataset; secondly, three standalone baseline models (LSTM, Transformer, and TCN), and two hybrid models, LT and LT, with PSO-optimized hyperparameters (P-LT) were constructed and trained to forecast the seakeeping performance of ships with multiple steps of 30, 60 and 90; finally, the comparison between solo and hybrid models was made by different steps on RMSE, MAE and NRMSE evaluations to prove the advancement of LT and P-LT models. The P-LT hybrid model achieved consistent accuracy improvements compared with the best-performing individual models across different ship motions. Notably, RMSE reductions were observed at all prediction horizons (30, 60, and 90 steps), with maximum improvements reaching 13.54% for rolling, 11.83% for pitching, and 12.87% for heaving motions. This study provides both theoretical and practical support to ship motion prediction and demonstrates the potential of the proposed study as an effective engineering product for enhancing safety in ship operation.
1. Introduction
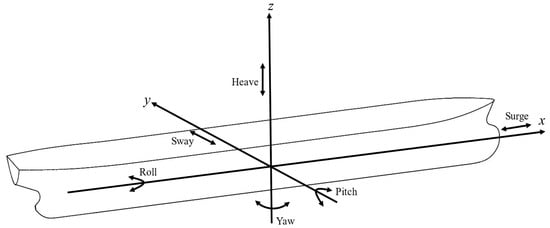
Driven by intensifying global warming and extreme weather patterns, ships are increasingly encountering severe, unpredictable, and rapidly changing sea states during service. Several research initiatives have been developed to address this challenge in ship seakeeping performance forecasting. The motion response of ships in waves is an essential determining factor for navigation safety and operational efficiency. Considering the six degrees of freedom in ship dynamics, as illustrated in Figure 1, the towing tank test remains the predominant method for seakeeping investigations. Researchers have used scaled model tests to extensively analyze complex phenomena, including the parametric rolling of containerships [1] and the dynamics of wave propagation within tank environments [2]. To evaluate performance under more complex environmental conditions, experimental approaches are often synthesized with theoretical frameworks—such as 3D hydroelasticity [3] or strip theory [4]—to distinguish motion responses in short-crested waves or to quantify key seakeeping indicators. Furthermore, different test setups, like surge-fixed and surge-free, have helped us measure extra resistance and local pressure more accurately [5]. Besides measuring physical data, new methods have been created to work well with noisy experimental data. These methods help build energetic models more accurately [6].
Figure 1.
Six degrees of freedom in ship motion.
Beyond model tests, data derived directly from real ships are invaluable, and researchers have employed diverse advanced methods to acquire and utilize such datasets. One approach involves real-time environmental sensing via onboard equipment; Lee et al. acquired 3D wave field data through radar image reconstruction to support a real-time digital twin system for coupled seakeeping-maneuverability simulations [7]. Another important source comes from long-term operation records. Schirmann et al. used a large dataset with over 15,000 offshore observations collected by two research ships. They combined these data with weather information to train strong prediction models based on physics [8]. Furthermore, dedicated sea trials serve as a critical data acquisition method, as demonstrated by Lou et al., who collected motion data directly via JARI-USV experiments to investigate how data acquisition parameters, such as sampling intervals, influence modeling accuracy [9].
Due to the remarkable development in CAE (computer-aided engineering), many studies using computational fluid dynamics (CFD) simulations focus on their outstanding efficiency and accepted accuracy. In hydrodynamic analysis, software such as ANSYS AQWA, which is built on three-dimensional potential flow theory and the boundary element method, is not only widely employed for computing the linear motions and wave loads of floating bodies but also provides high-quality datasets that support the training of data-driven models. Chen et al. investigated an important working model of the AUH approaching a host ship in waves with ANSYS-AQWA in 2019 [10]. Miao et al. used ANSYS-AQWA as a reference to validate the in-house code THAFTS-NATD, and reported very close agreement in heave and pitch responses and decay functions, confirming the reliability of the AQWA solutions [11]. Trang et al. showed that AQWA accurately captures the increase in roll RAO peaks with ship speed for a vessel equipped with an underwater turbine support, thereby demonstrating its validity for ships with additional structural appendages [12]. In 2022, Sun et al. used the DTMB 5415 ship as the study case and employed AQWA to validate the motion responses of an MMG model in regular waves; the computed heave and pitch RAOs differed from experimental measurements by less than 8%, thereby confirming the effectiveness of the proposed research framework [13]. Hu et al. adopted AQWA to compute hydrodynamic coefficients of DTMB 5415 and used these results as a benchmark for validating state-space model parameters, relying on the software’s previously verified accuracy in ship motion and wave load analysis in 2023 [14]. Mikkelsen et al. treated an AQWA-generated database as trusted reference data for training physics-informed machine learning models of hydrodynamic coefficients [15]. Nazemian et al. employed the three-dimensional panel method implemented in ANSYS-AQWA to obtain reliable seakeeping responses of a trimaran for subsequent simulation-based design [16].
Commercial CFD software based on computational continuum mechanics, such as STAR-CCM+, NUMECA, and ANSYS Fluent, based on the Reynolds-averaged Navier–Stokes (RANS) equations and the volume of fluid (VOF) method, is well suited for problems involving strongly nonlinear fluid–structure interaction, added structural effects, and detailed flow-field resolution. In 2020, Jiao et al. employed STAR-CCM+ to construct a numerical wave tank for the S175 container ship in bidirectional crossing seas, successfully capturing the sharp increase in roll amplitude and green water on deck with prediction errors below 10% [17]. In 2025, Hong et al. used STAR-CCM+ to simulate the high-speed planing behavior of a catamaran unmanned surface vehicle (USV) and to resolve the details of wave-impact phenomena on the hull [18]. In 2024, Copuroglu et al. combined particle image velocimetry (PIV) measurements with STAR-CCM+ simulations to investigate the roll-damping effects of bilge keels of different shapes and found that sharp-edged geometries can increase the roll-damping coefficient by about 25% [19]. In 2025, Kim et al. applied STAR-CCM+ to validate the effectiveness of a pair of hydrofoils in suppressing heave and pitch motions of a monohull vessel [20].
Today, the significantly reduced cost of seakeeping data, from real ships to experiments to simulations, encourages investigators to focus on data-driven time series forecasting methods. Early studies focused on recurrent neural networks (RNNs), introduced by [21], which use feedback connections to model sequential dependencies effectively. To address the vanishing gradient problem and enable the learning of long-range dependencies, Hochreiter [22] subsequently developed the Long Short-Term Memory (LSTM) architecture. More recently, the Transformer model proposed by Vaswani et al. [23], based solely on self-attention mechanisms, has set a new benchmark by enabling parallelization and modeling global context.
These architectures have been extensively applied to ocean engineering. RNNs and their variants have shown robust performance; for instance, RNNs with Bayesian Regularization were found to outperform feed-forward networks in predicting significant wave height (SWH) [24,25]. Sadeghifar et al. [26] reported high correlation coefficients (up to 0.96) for near-term forecasts using RNNs. However, capturing short-term fluctuations remains challenging for basic models [27]. Consequently, LSTM networks became a dominant tool. Fan et al. [28] and Ni & Ma [29] demonstrated the superiority of LSTMs over traditional machine learning models. Abdullah et al. [30] confirmed the effectiveness of LSTM for significant wave height forecasting in Indonesian waters. To address the gap in multivariate wave forecasting, Wei [31] proposed an artificial intelligence model that simultaneously predicts significant wave height, average wave period, and mean wave direction using a broad set of meteorological inputs.
Comparative studies have further clarified the applicability of these models in a case study in Indonesia. Putri and Adytia [32] compared Transformer and LSTM models, finding that while Transformers performed well, LSTM models held a slight advantage for horizons of 3 to 30 days. Conversely, for continuous forecasting, Shi et al. [33] demonstrated that an attention-based Transformer model significantly outperformed both LSTM/GRU models and traditional numerical models (MASNUM) for predictions up to 72 h ahead. Parallel to wave forecasting, these methods were adapted for ship motion prediction. Yang et al. [34] successfully applied reservoir computing to predict the motions of a moored barge. Furthermore, recent studies have increasingly adopted Transformer-based models to integrate multi-source data for 6-DoF ship motion prediction [35], or to leverage spatiotemporal networks like EarthFormer [36] and GEFS-integrated models [37] for high-efficiency oceanographic forecasts.
To overcome the limitations of individual model methods, hybrid approaches have emerged as a robust solution in seakeeping forecasting. These models generally fall into three categories: architectural fusion, mechanism enhancement, and physics-optimization integration. The first category focuses on fusing different neural architectures to leverage their respective strengths, particularly the spatiotemporal capabilities of CNNs and LSTMs. Early efforts focused on simple linear–nonlinear collaboration, but recent research has shifted towards deep coupling. Zhang et al. proposed a CNN-LSTM coupled model [38], utilizing CNNs for spatial feature extraction and LSTMs for long-term dependencies. Similarly, Li et al. achieved deep synergy in a CNN-LSTM hybrid, realizing high-precision ultra-short-term prediction (2 s ahead) under Sea State 6, satisfying real-time wave compensation requirements [39]. Targeting high sea states, Zhang et al. developed the ConvLSTMPNet parallel model, which decouples wave–ship interaction features from hydrodynamic memory effects to achieve cycle-level multi-step prediction. The second category enhances models by incorporating advanced learning mechanisms [40]. To address the unidirectional information loss in standard LSTMs, Wang et al. employed Bidirectional LSTM (Bi-LSTM) combined with a temporal pattern attention (TPA) mechanism [41]. Furthermore, Li et al. integrated a “teacher forcing” technique into an encoder–decoder Bi-LSTM network [42], significantly extending the effective prediction horizon for ship roll motion up to 120 s. The third category integrates physical principles or optimization algorithms to boost performance. Marlantes et al. developed a neural correction model that fuses low-order physical terms with machine learning corrections, enhancing interpretability [43]. In terms of algorithmic optimization, Sun et al. introduced a BP-BiLSTM parallel model to combine nonlinear mapping with bidirectional temporal extraction [44]. More recently, Yuan et al. proposed a hybrid model combining the Sparrow Search Algorithm (SSA) with BiLSTM, demonstrating superior accuracy in forecasting roll and pitch motions across varying wave periods compared to standard baselines [45]. Furthermore, new studies look at using physics-based methods like dynamic mode decomposition (DMD) with neural networks. These methods help make models smaller and easier to understand. One example is DMD-based neural operators that estimate partial differential equations [46]. By integrating various strengths, these hybrid philosophies are driving the creation of more accurate, interpretable, and resilient predictive models essential for effective seakeeping forecasting.
Ship motions operate under two conflicting forces: strict rigid-body inertia constraints and complex wave excitation. This duality demands a local–global modeling perspective that captures both stepwise inertial dynamics and broader temporal dependencies. Although hybrid architectures combining recurrent networks and attention mechanisms appear in time series forecasting, current marine hydrodynamics research often relies on parallel strategies. These strategies often fail to account for the kinematic hierarchy that governs ship movement.
To address this, the present study introduces a serial kinematic–contextual decoupling framework, designed around a physically informed hierarchical inductive bias. The architecture assigns distinct roles: the LSTM encoder maintains kinematic continuity and attenuates high-frequency fluctuations, while the Transformer decoder processes the full temporal context to reduce phase lag. Testing under mixed sea-state conditions and multiple horizons allows us to evaluate the method’s success in balancing stability and accuracy. Finally, the system includes adaptive hyperparameter optimization to handle task-dependent variability and boost robustness across different settings. The main contributions of this paper are as follows:
- (1)
- We propose a serial kinematic-contextual split with an LSTM–Transformer encoder–decoder. This matches the physical order of inertia and wave effects. It makes a local–global model that goes beyond stacking layers.
- (2)
- To demonstrate the necessity of our network, we compare different networks for their predictive performance in mixed sea states.
- (3)
- We add adaptive hyperparameter tuning. This handles different motion types. It makes the model stronger and more reliable by adjusting for each task.
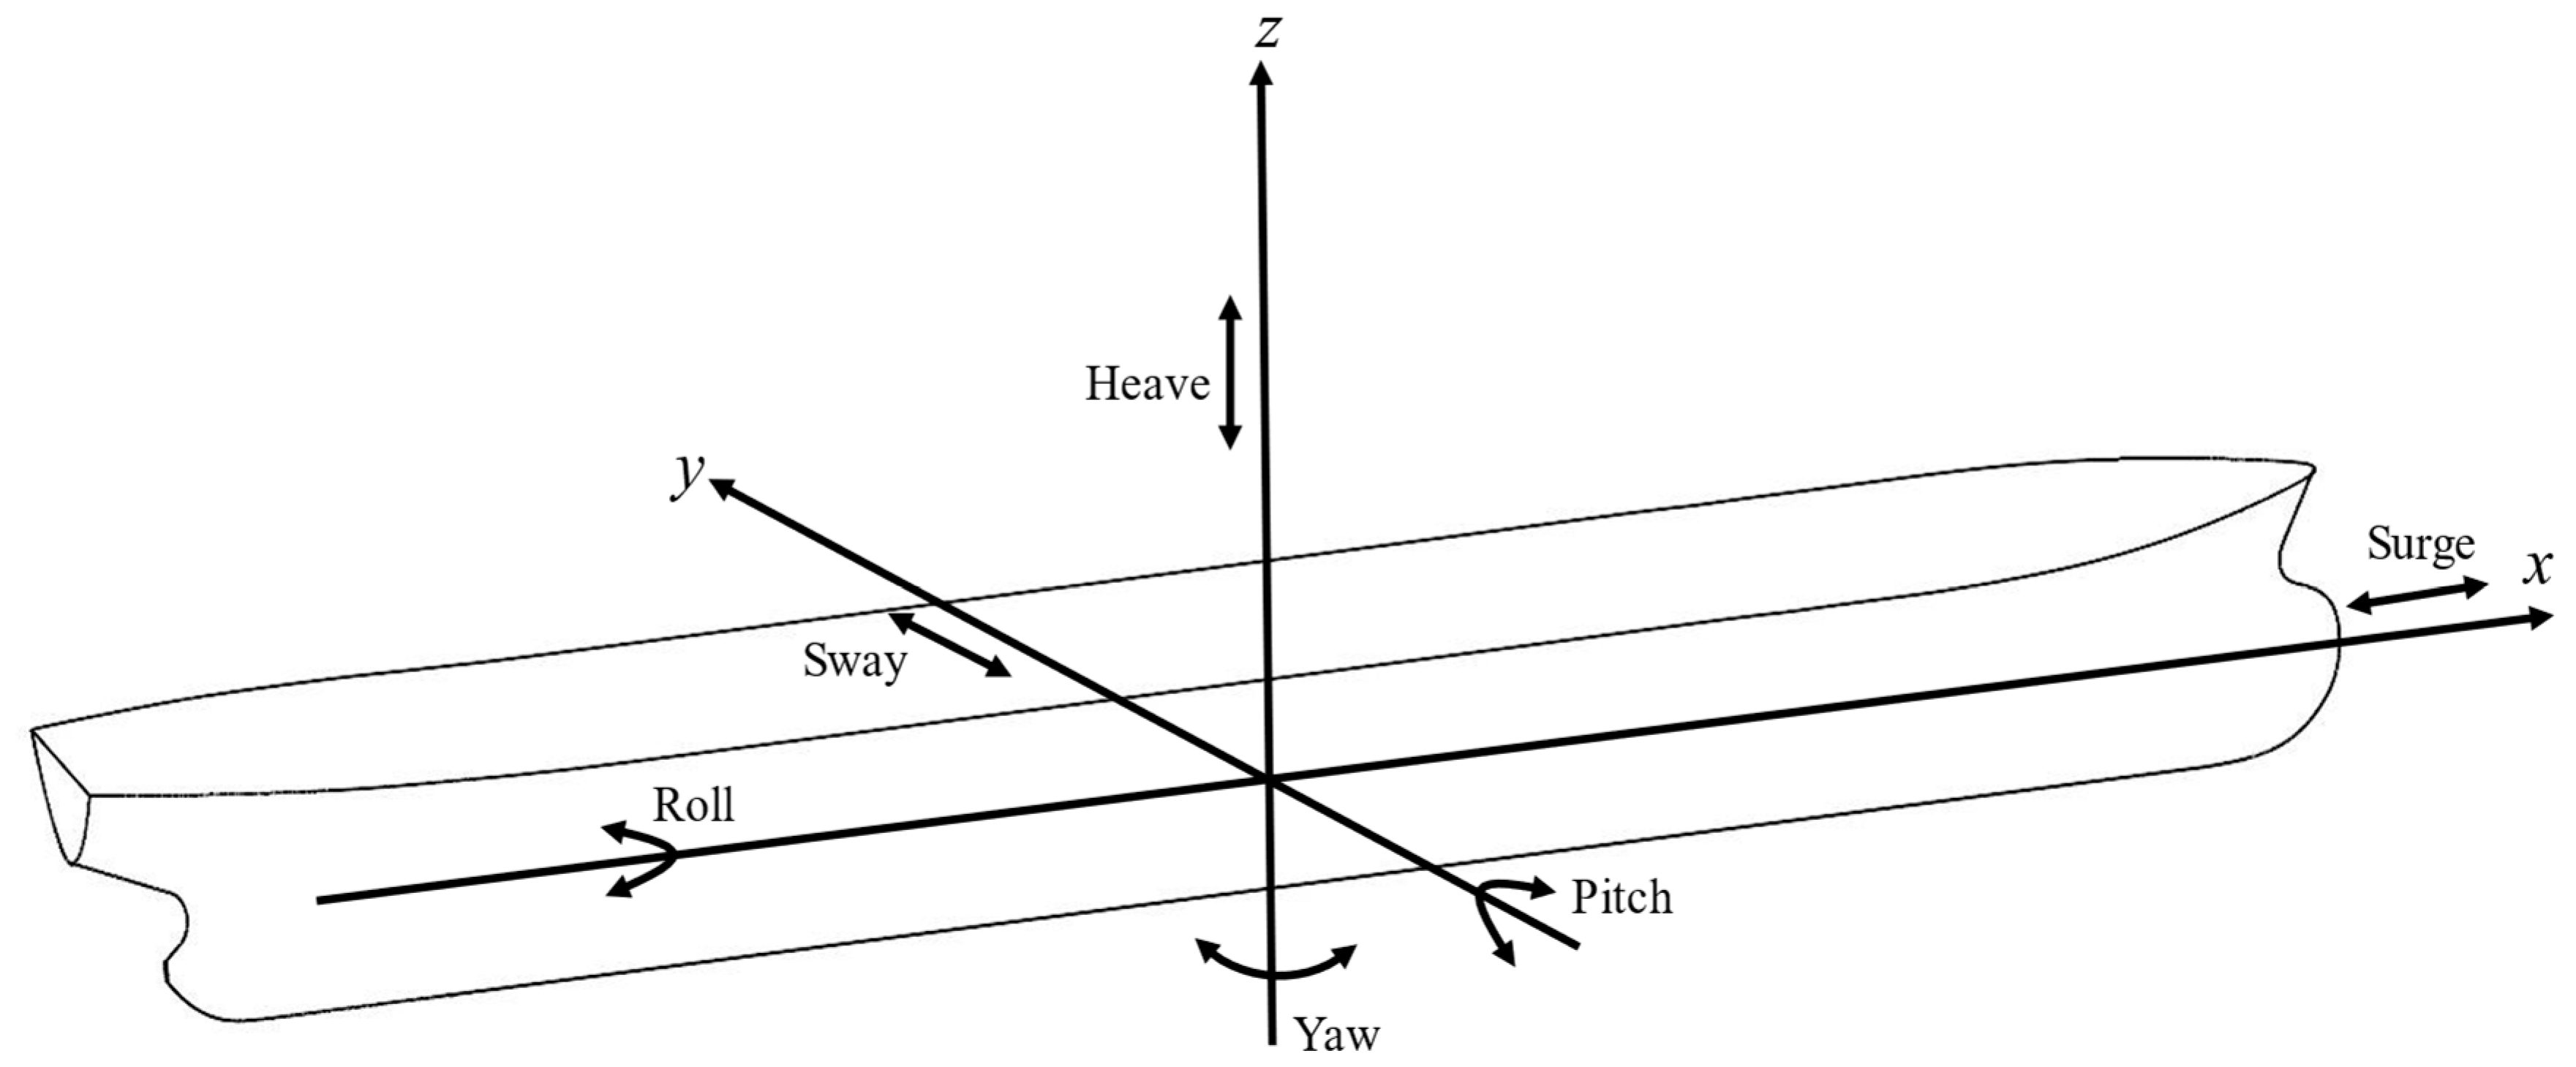
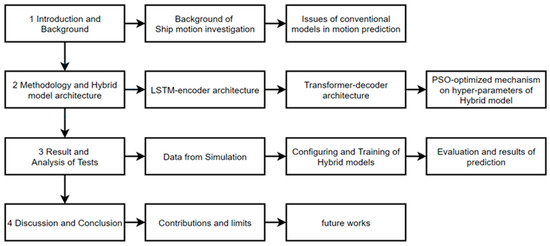
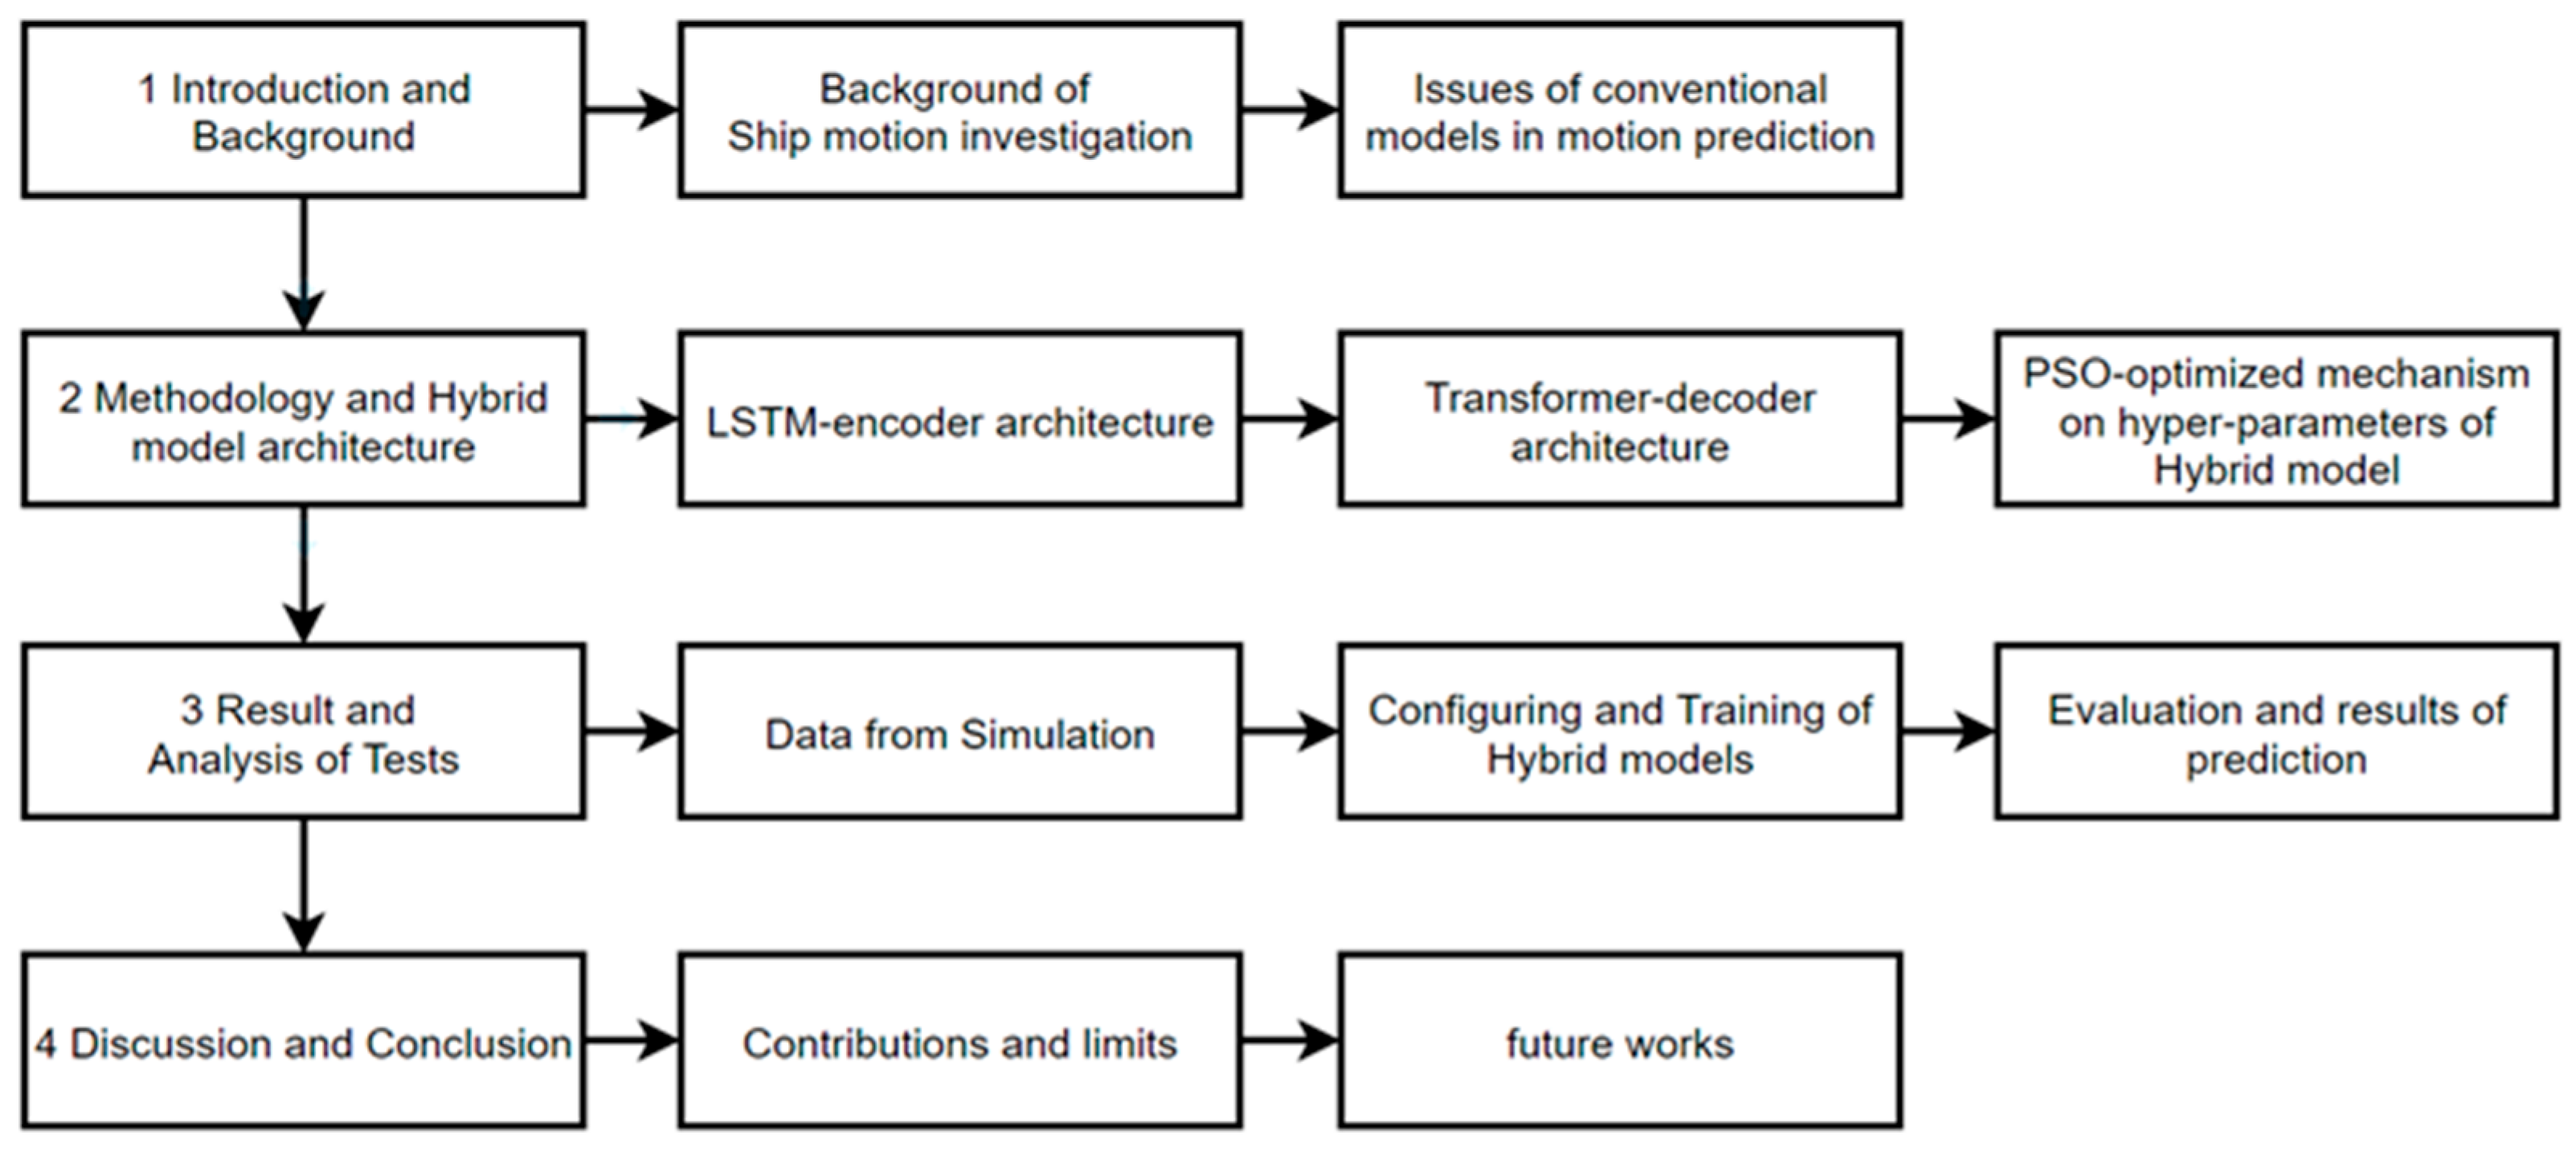
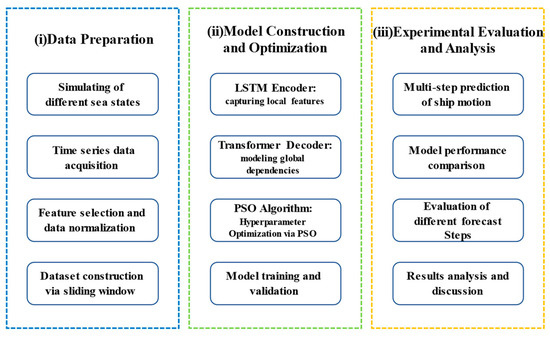
The rest of this paper is organized as shown in Figure 2. Section 2 elaborates on the overall framework and underlying mechanisms of the proposed model, including the LSTM encoder, Transformer decoder, and PSO optimization algorithm. Section 3 presents the experimental results and analysis, specifically covering the construction of mixed datasets through simulation, the parameter configuration for model training, and the implementation and result analysis of multiple sets of comparative experiments. Finally, Section 4 summarizes this paper and then elaborates on directions for future research.
Figure 2.
Architecture of this article.
2. Methodology and Hybrid Model Architecture
2.1. Overall Framework and Research Methodology
The prediction of ship roll, pitch, and heave motions constitutes a time series modeling problem characterized by time-varying properties. Its essence lies in constructing a mapping relationship from historical observation sequences to future states. Let the historical observation window length be , and the prediction step length be . This can be formally expressed as follows:
where represents the historical observation sequence of length , denotes the predicted values for the next steps, and is the mapping function to be learned.
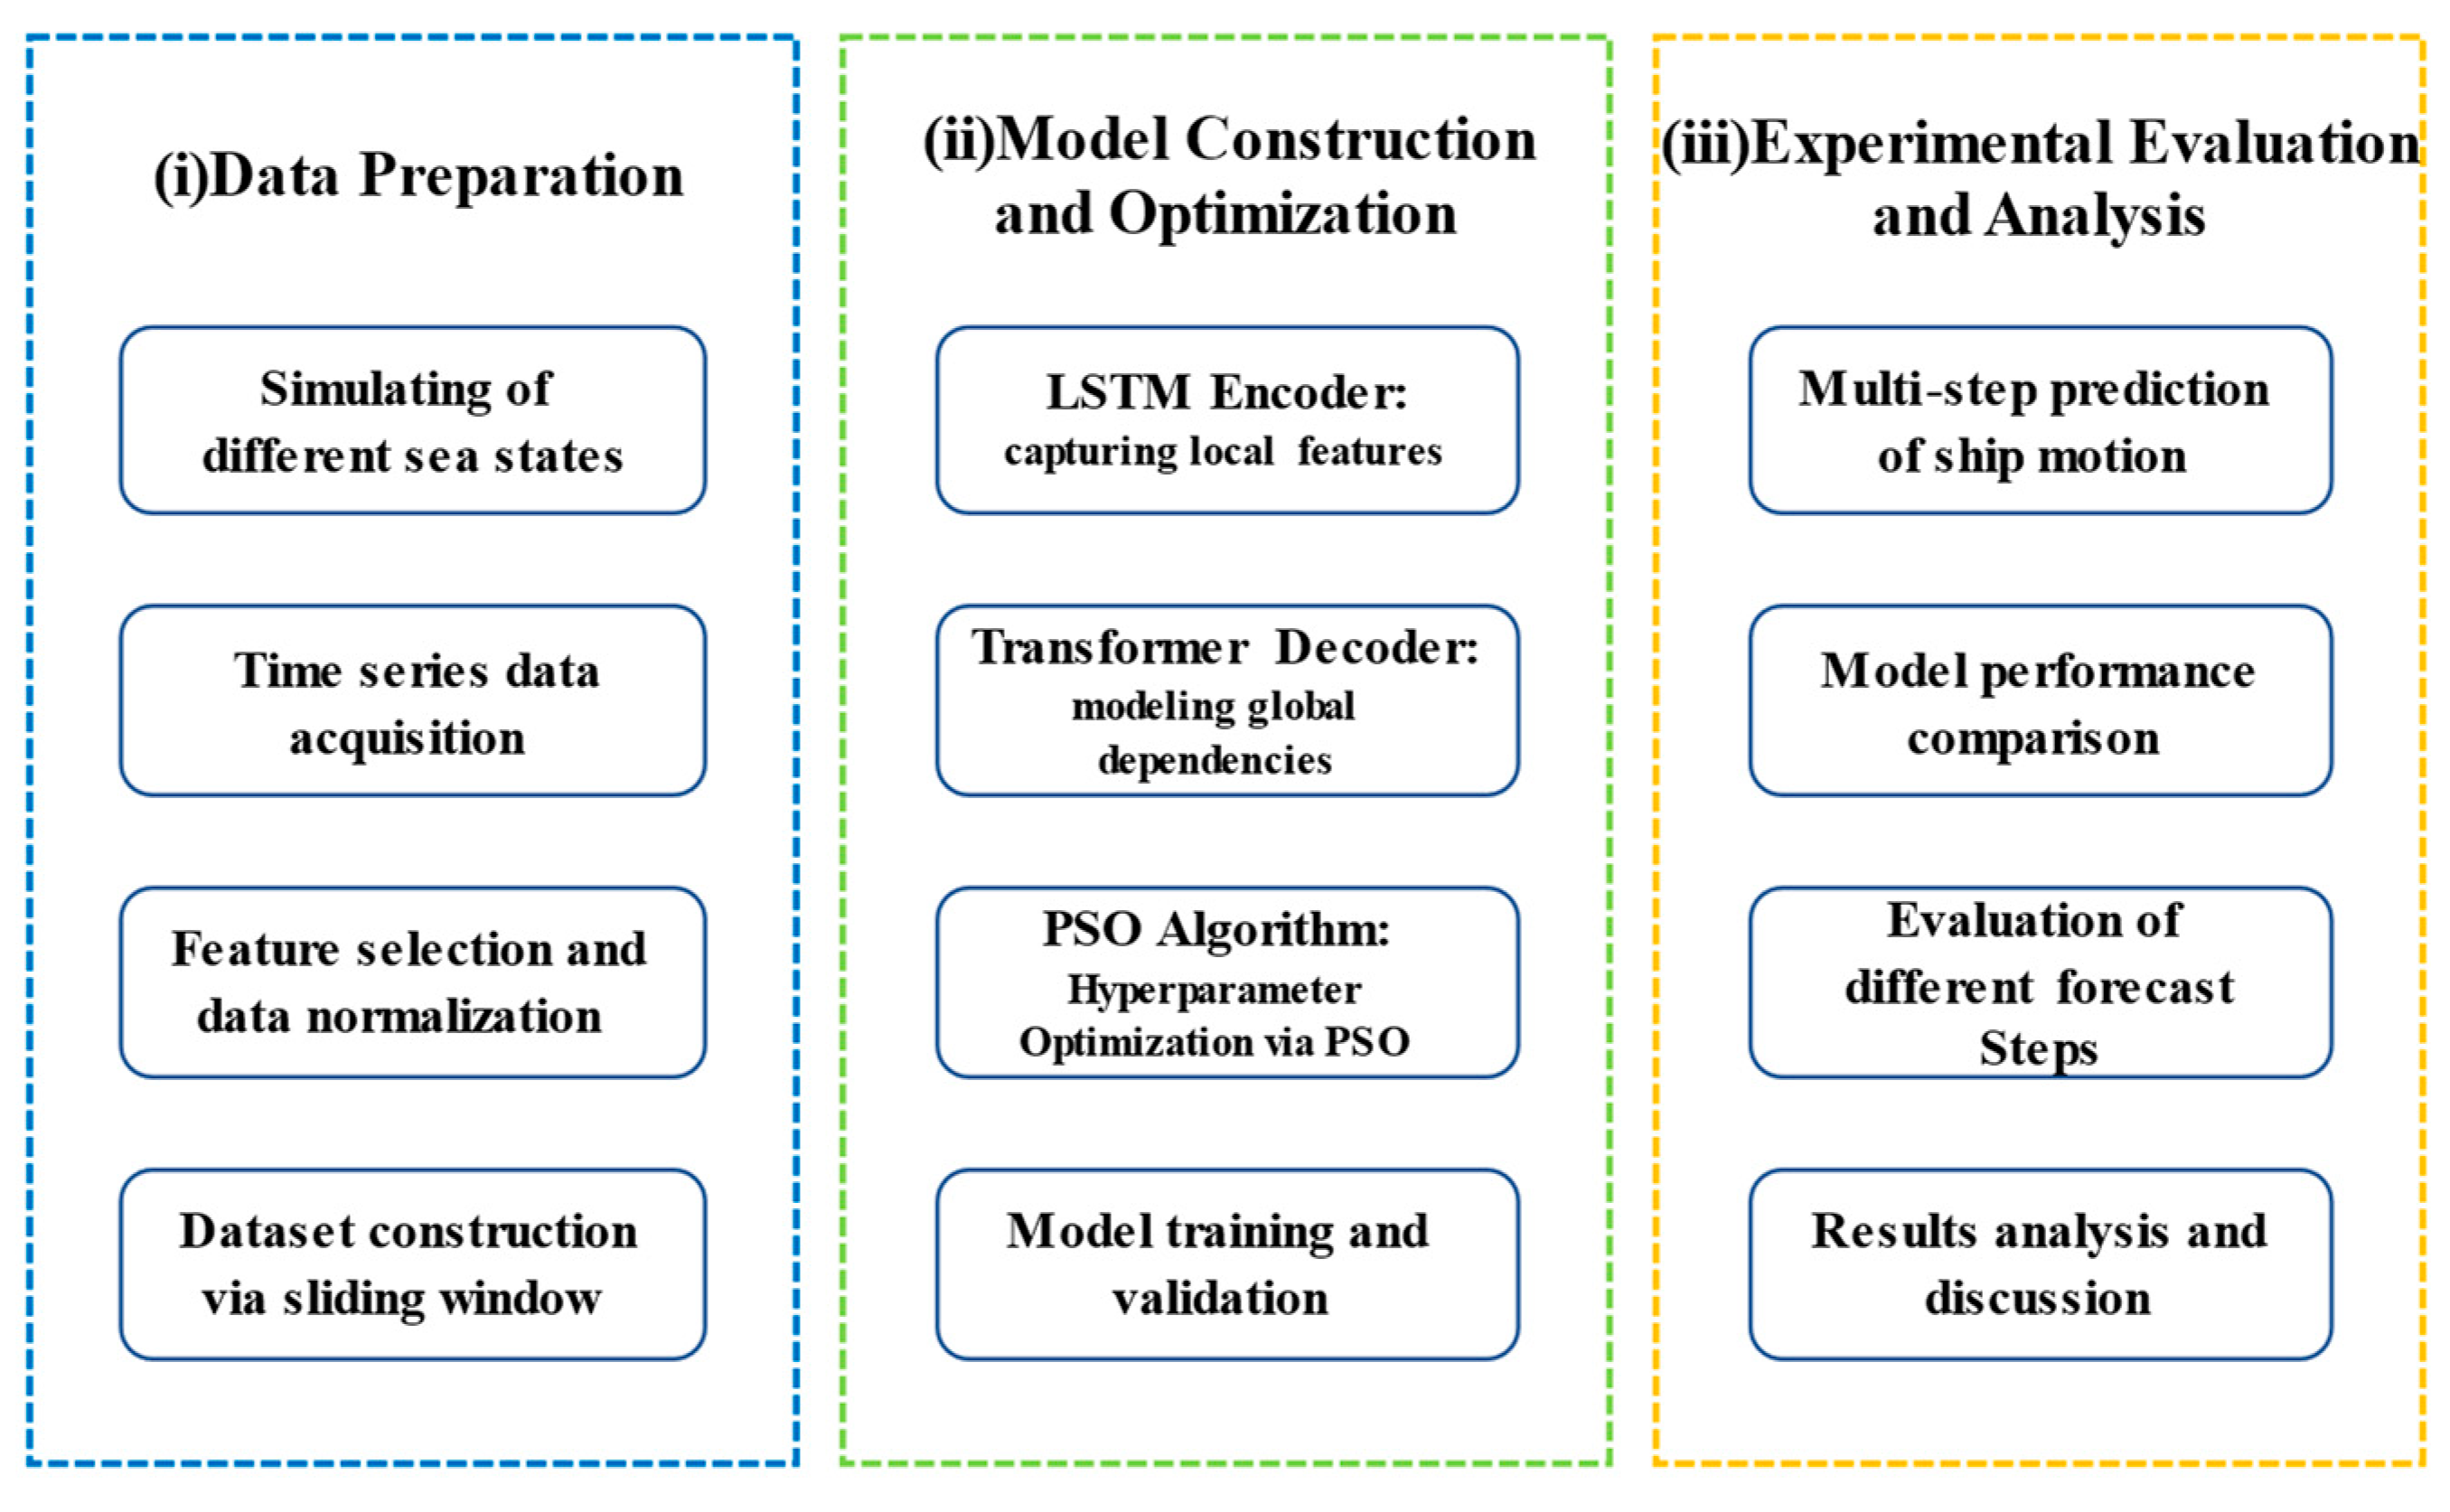
This paper introduces a hybrid prediction framework to capture the complex dynamics of ship motion and ensure reliable performance across varying sea conditions. The proposed framework is formulated based on a serial kinematic–contextual decoupling strategy, in which ship motion dynamics are decomposed into stepwise inertial dynamics and complex wave-driven excitation patterns within a unified encoder–decoder structure. The overall research methodology, as depicted in Figure 3, primarily spans the following stages: Initially, data are generated through simulation, followed by meticulous feature selection and normalization. Subsequently, the preprocessed data are fed into the proposed hybrid neural network model. This network comprises an LSTM–Transformer encoder–decoder structure. To further optimize model performance and ensure adaptability to various prediction tasks, the particle swarm optimization (PSO) algorithm is introduced for adaptive optimization of critical model hyperparameters. Finally, the effectiveness of the proposed framework is rigorously validated through a series of experiments, including comparative analyses with different existing models and an evaluation of its prediction performance for roll, pitch, and heave motions across varying output prediction lengths.
Figure 3.
Research methodology.
2.2. Proposed Hybrid Framework
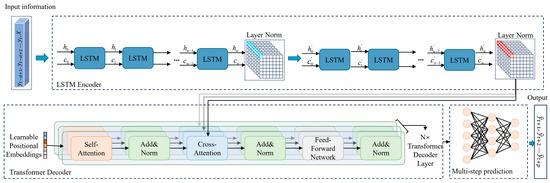
The framework centers on a hybrid encoder–decoder architecture that incorporates a physically informed hierarchical inductive bias. Instead of simply stacking layers or treating the ship correct motion as a homogeneous time series, the architecture involves serial kinematic–contextual separation. The LSTM encoder promotes kinematic continuity by incorporating rigid-body inertia constraints, effectively suppressing spectral high-frequency components. Meanwhile, the Transformer decoder captures comprehensive temporal patterns driven by wave excitation to reduce phase lag. This structural decoupling aligns deep learning dynamics with the physical generation mechanism of ship motions. As illustrated in Figure 4, the LSTM encoder is responsible for capturing local dynamic features and short-term temporal dependencies from the input sequence, outputting a sequence of context vectors that encapsulate this information. This vector sequence is subsequently passed to the Transformer decoder, which utilizes it as input for its cross-attention mechanism to model the global long-term dependencies and evolutionary trends of the sequence. Finally, the decoder’s output is processed by a fully connected neural network (FCNN) to generate the multi-step prediction results.
Figure 4.
Hybrid model architecture.
2.2.1. LSTM–Encoder Architecture
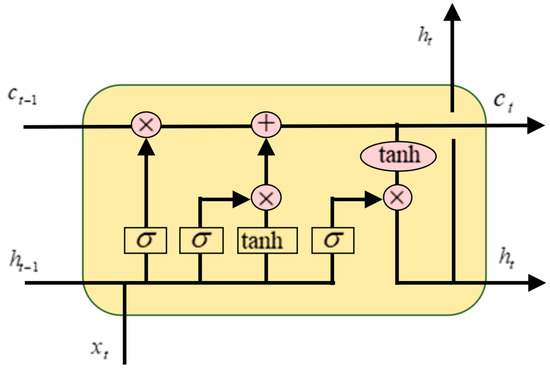
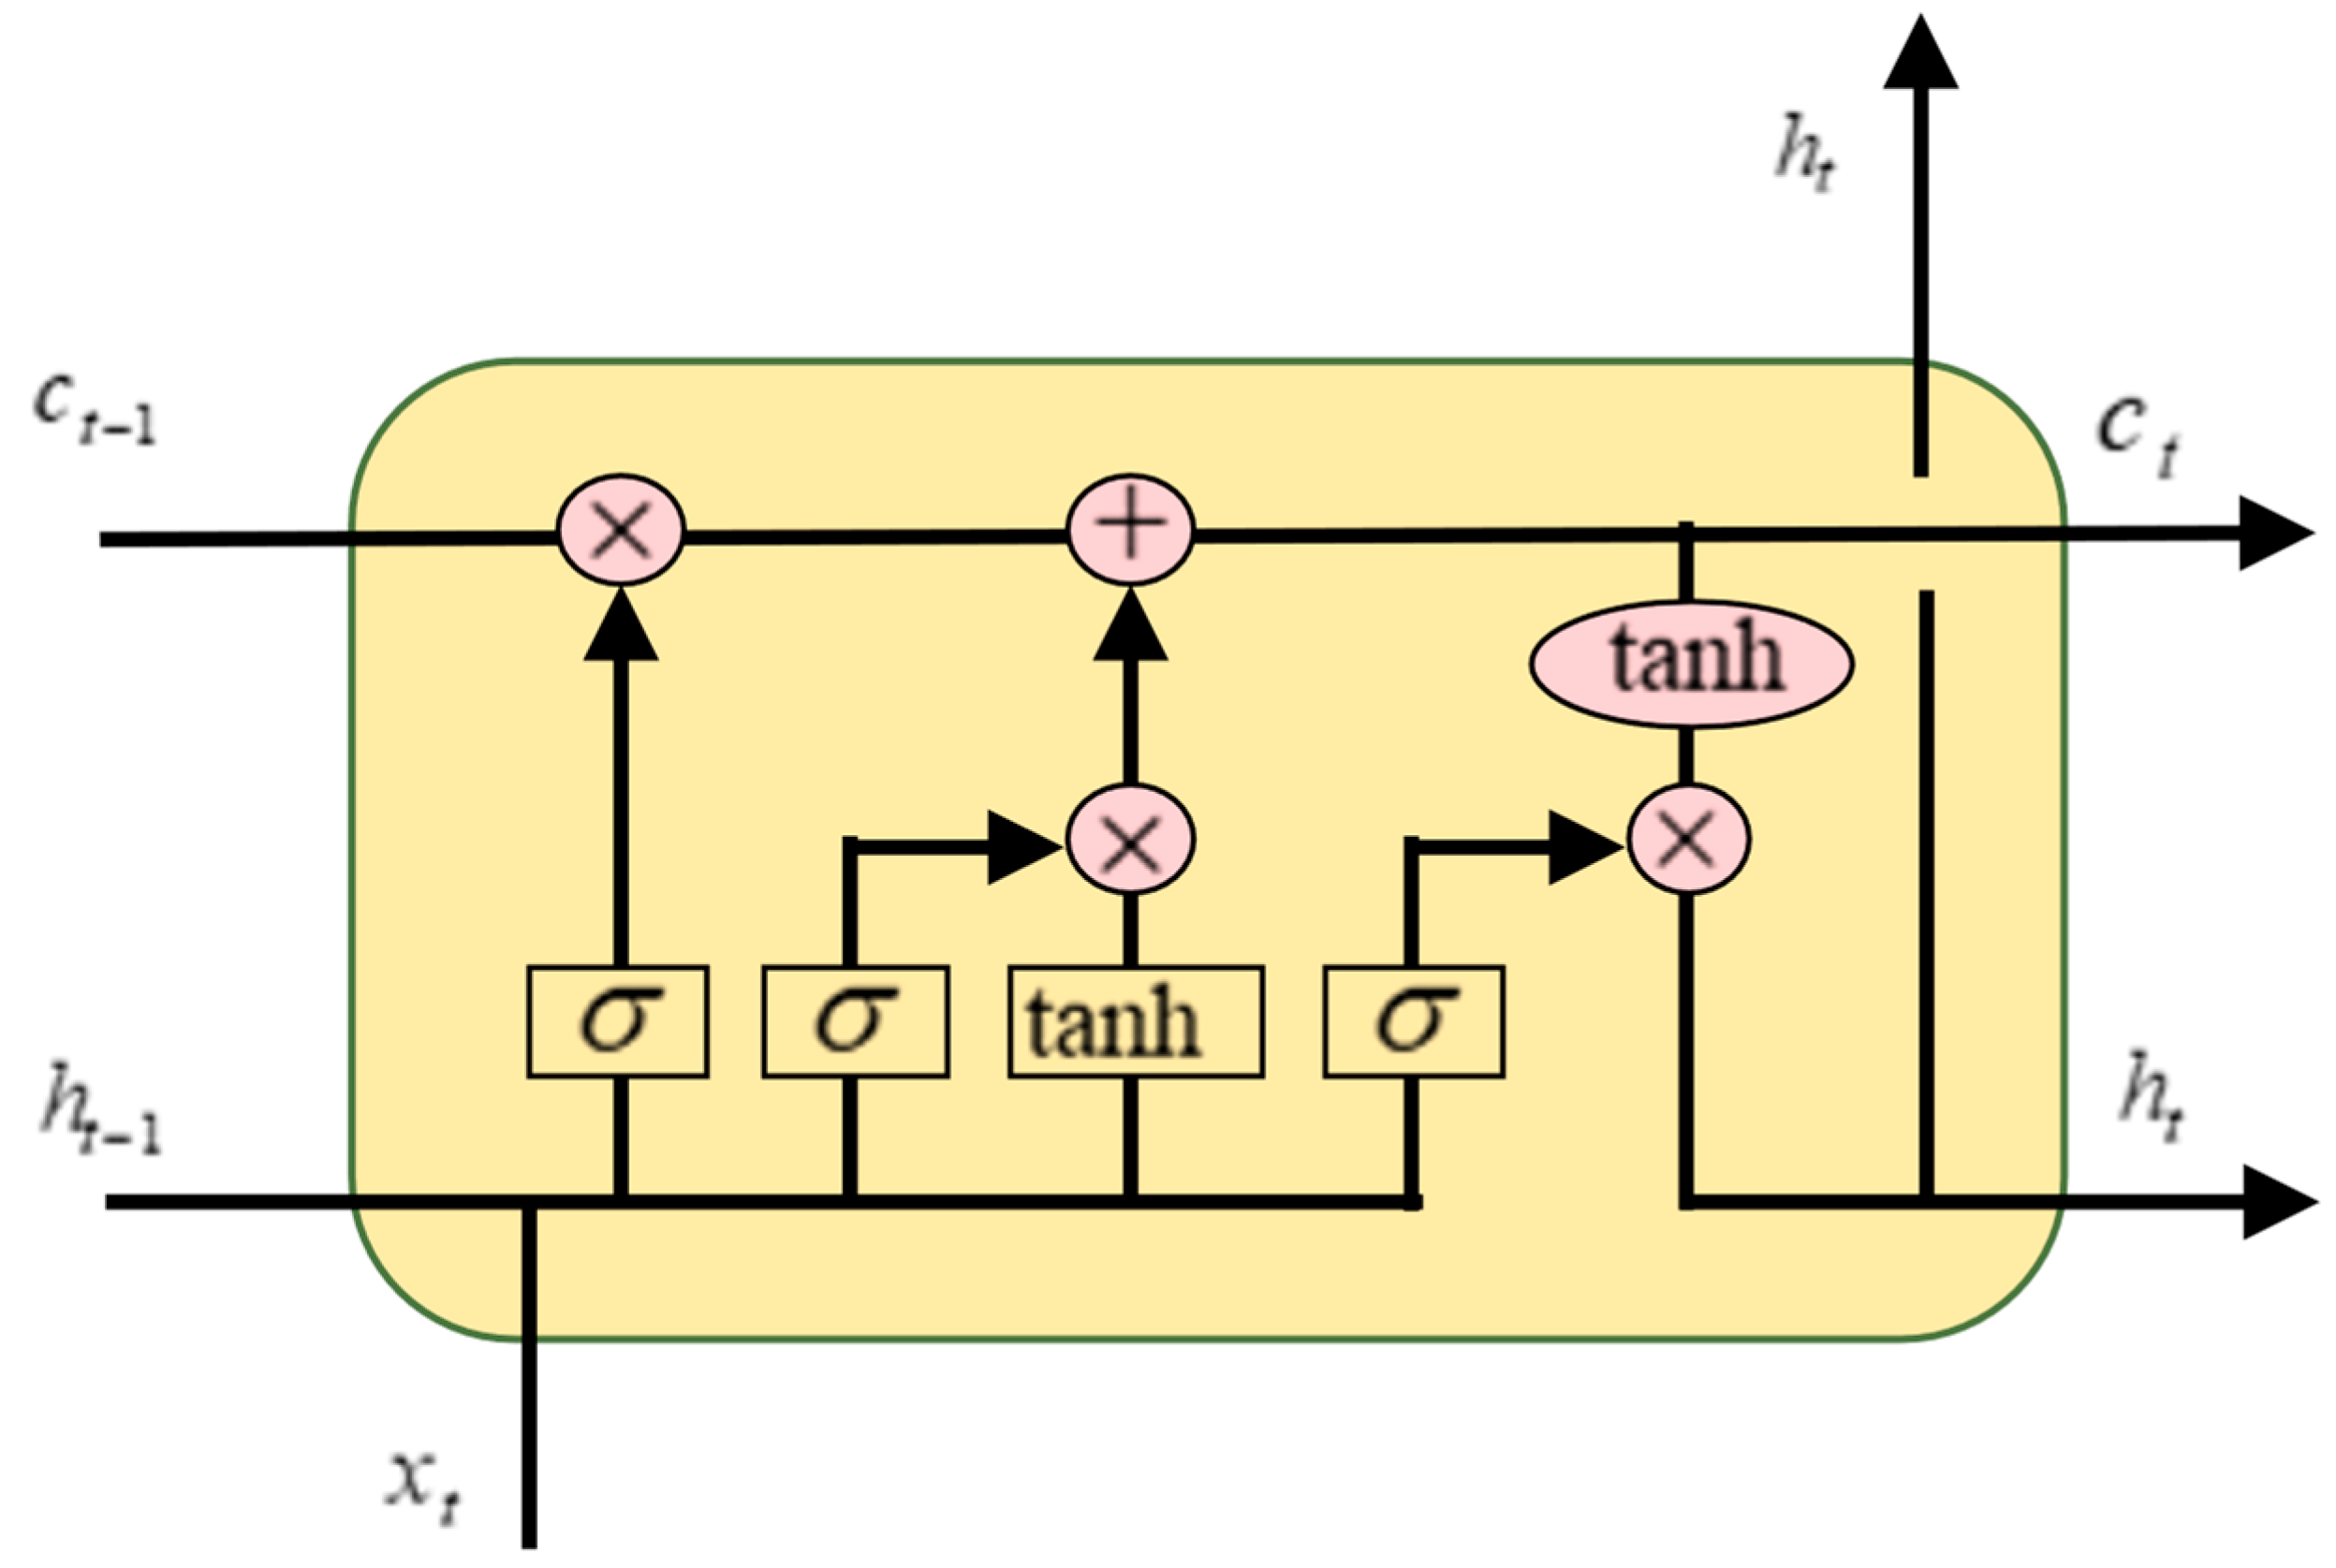
The encoder component is constructed by stacking multiple layers of unidirectional LSTMs, tasked with transforming the input historical observation sequence into a set of hidden state vectors rich in temporal information. Figure 4 illustrates the LSTM encoder unrolled across the temporal dimension, demonstrating how the hidden states evolve step-by-step alongside the input sequence. While Figure 5 depicts the internal gating mechanism of a standard LSTM unit, our architecture explicitly applies layer normalization to the output of the LSTM layers (as visualized in the sequential flow of Figure 4). This normalization step standardizes the hidden states to mitigate gradient issues and enhance training stability.
Figure 5.
Diagram of LSTM.
LSTM units implement long short-term memory modeling based on a gating mechanism. Among these, the memory cell serves as the core information carrier, responsible for transmitting and storing long-term memory across the temporal dimension. Its content is selectively updated through the collaborative action of the forget gate and the input gate. The forget gate, via a sigmoid activation function, controls the degree to which historical information is retained; the input gate regulates the amount of current input information written into the cell state; and the output gate determines the content of the hidden state output based on the current cell state and input.
This sophisticated gating structure effectively mitigates the vanishing and exploding gradient problems encountered during backpropagation, enabling robust modeling of short-term temporal correlations and local dynamic response patterns in ship motion sequences. The computational process of the integrated layer normalization LSTM encoder can be simply expressed as
where is the input vector at time step , and and represent the hidden state and memory cell state of the LSTM, respectively. The encoder constructs temporal inputs through a sliding window mechanism, extracting short-term dependencies and local dynamic features from the sequence, and outputs the encoded hidden state sequence, providing the foundational input for the subsequent Transformer decoder. In the proposed framework, the LSTM encoder functions as the component enforcing kinematic constraints. It captures the underlying stepwise inertial dynamics to enforce continuity and mitigate spectral noise, providing a stable contextual representation for subsequent processing.
2.2.2. Transformer–Decoder Architecture
In the proposed framework, the Transformer decoder actively models comprehensive wave excitation patterns by using the kinematic context generated by the LSTM encoder. By analyzing the entire encoded motion sequence, the decoder effectively captures complex long-term dependencies, enabling it to reduce phase lag and balance the trade-off between stability and accuracy in wave-driven motions. The decoder utilizes an improved non-autoregressive Transformer architecture, which departs from the sequential, step-by-step generation of traditional autoregressive models. It instead employs a parallel decoding strategy, capable of simultaneously generating predictions for all target timesteps. This design effectively leverages the Transformer’s attention mechanism while significantly enhancing inference efficiency and reducing the error accumulation problem inherent in autoregressive models.
In this design, the non-autoregressive decoder operates without reliance on previously generated outputs. Instead, it directly uses learnable positional embeddings as initial input, which serve as independent query vectors for each target time step and are defined as follows:
where is the batch size, is the initialization standard deviation for the learnable positional embeddings, and represents the matrix of these learnable positional embeddings.
Each decoder layer consists of three main sub-layers, each followed by a residual connection and layer normalization. The first sub-layer is the multi-head self-attention mechanism. Here, the Query, Key, and Value are all derived from the input positional embeddings (for the first layer) or the output of the preceding sub-layer (for subsequent layers). This self-attention allows the decoder to capture relationships among different target timesteps. Secondly, the output of the self-attention sub-layer (after residual connection and layer normalization) is passed to the multi-head cross-attention mechanism. This serves as the core of information interaction between the encoder and decoder. In this sub-layer, the Query originates from the decoder’s intermediate representation, while both Key and Value are derived from the complete contextual vector sequence output by the LSTM encoder. Its computation process can be formalized as follows:
where , , and are the parameter matrices for the attention heads.
Finally, following the cross-attention sub-layer, the output is then processed by a feed-forward network (FFN) sub-layer. This network consists of two linear transformations interspersed with a Gaussian error linear unit (GELU) activation function, performing further nonlinear mapping of features to enhance the model’s expressive power. Unlike the rectified linear unit (ReLU), which applies hard thresholding at zero, GELU provides smooth, probabilistic gating that allows better gradient flow and is particularly effective in Transformer architectures. Its computation is given by
where and are weight matrices; and are bias terms.
2.3. PSO-Optimized Hyperparameters
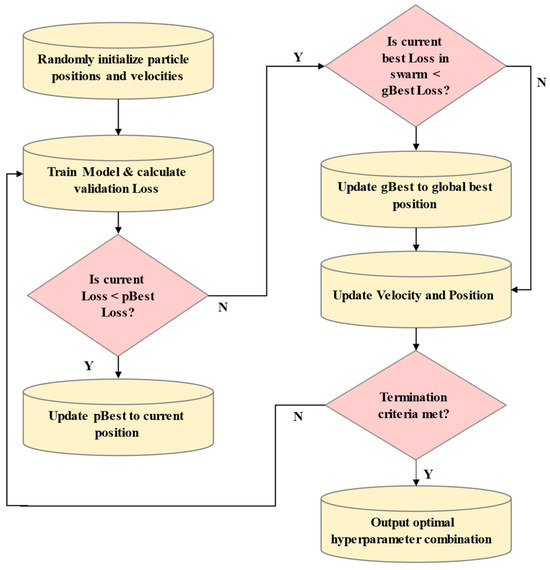
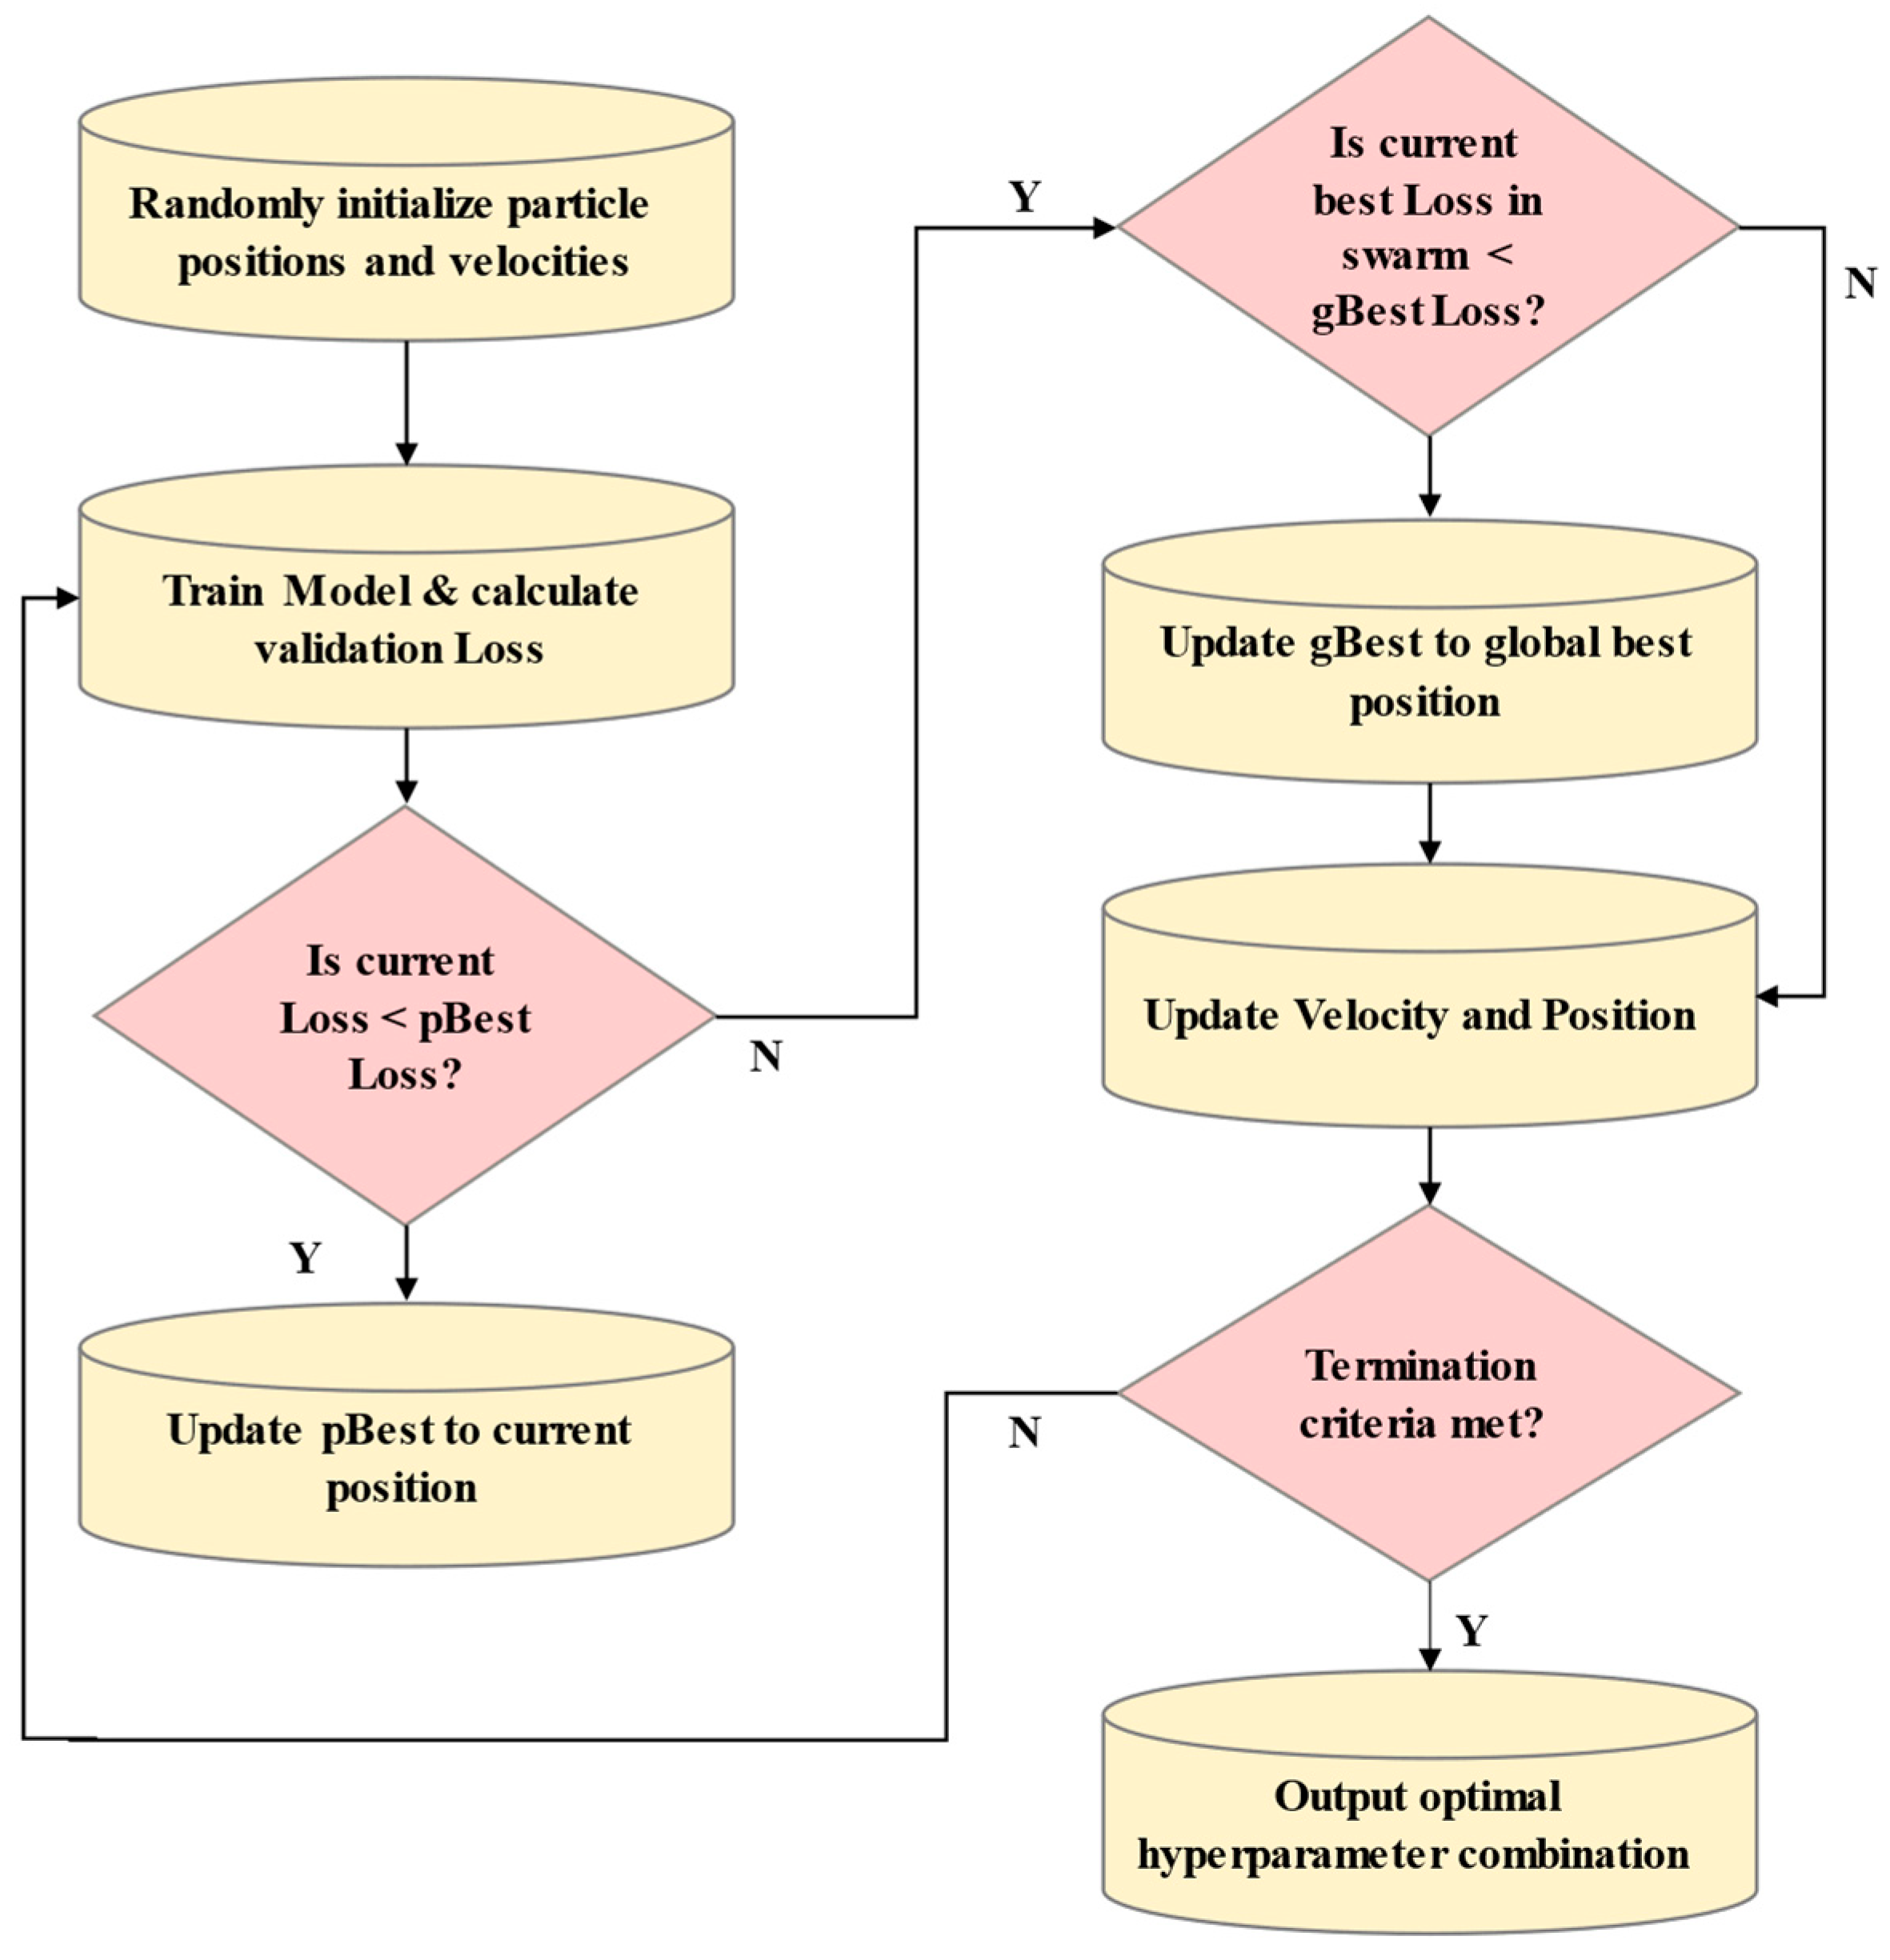
To further enhance the forecasting performance and generalization adaptability of the proposed hybrid model, it is beneficial to employ a particle swarm optimization (PSO) algorithm to construct an adaptive hyperparameter optimization mechanism. This algorithm efficiently explores the optimal configuration in the hyperparameter space by simulating the collaborative search and information sharing observed in natural particle swarms. The overall optimization process is illustrated in Figure 6.
Figure 6.
Flowchart of the PSO optimizer.
Hyperparameter optimization in this study considers the impact on model performance and computational efficiency, and five hyperparameters were ultimately selected. The ranges and physical meanings of each hyperparameter are as follows:
- (1)
- Learning Rate (lr): As a crucial step size parameter for the optimizer to update model weights, the learning rate directly influences the convergence speed and stability of the model. An excessively high learning rate can lead to training oscillations or even gradient divergence, while an excessively low learning rate can significantly reduce convergence speed and increase training costs. Therefore, fine-tuning is necessary to achieve fast and stable convergence. In this study, searches are performed within the interval using a log-uniform distribution. This range covers the reasonable step size interval required for rapid model convergence, and the logarithmic distribution characteristic enhances the search density in the low learning rate region.
- (2)
- Dropout Rate (dropout): By randomly masking the outputs of a portion of neurons during training, the dropout mechanism effectively suppresses model overfitting and forces the network to learn more robust generalization features. To balance model expressive capacity and generalization ability, its search range is set to [0.1, 0.3].
- (3)
- Hidden Dimension (hidden_size): This parameter determines the complexity of internal feature representations and the information encoding capability of the LSTM encoder and the Transformer decoder. Its value directly affects the depth and breadth of feature learning. A larger hidden dimension can capture more complex data patterns, but leads to increased computational overhead and a higher risk of overfitting. In this study, searches are performed within the range with a step size of 64. This discretization ensures the dimension is an integer multiple of the number of attention heads for architectural consistency.
- (4)
- Number of Attention Heads (nhead): As an essential parameter of the multi-head attention mechanism in the Transformer decoder, the number of attention heads determines the model’s ability to learn information from different representation subspaces in parallel. This effectively supports the capture of complex multi-scale temporal dependencies and critically influences the depth at which the model understands the input context. Balancing model performance and computational cost, we set its candidate values to {4, 8, 16, 32}.
- (5)
- Number of Transformer Layers (layers): This parameter defines the network depth of the Transformer decoder and directly impacts the model’s hierarchical feature extraction capabilities. Increasing the number of layers helps the model learn more abstract and higher-order temporal dependencies, enhancing its ability to model complex data patterns. However, it also significantly increases computational burden and training difficulty. Therefore, we limit its search range to the integer interval {1, 2, 3}.
To effectively handle these discrete hyperparameters (e.g., nhead and layers) within the continuous search space of PSO, a probabilistic jumping mechanism is introduced. Instead of direct positional updates, this method maps the particle’s velocity to the probability of state transitions, enabling the optimizer to explore discrete configurations robustly. The detailed parameter settings for the PSO algorithm are presented in Table 1.
Table 1.
Parameter configuration of the PSO algorithm.
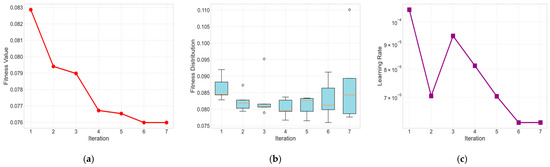
The fitness function was defined as the minimum validation loss (SmoothL1Loss) observed during this training process. Local and global optima were subsequently updated based on their fitness values. Before determining the final hyperparameters, an in-depth analysis of the PSO optimization process was conducted to evaluate its convergence efficiency and stability. Taking the 90-step rolling prediction task as a representative example, the optimization dynamics are illustrated in Figure 7. As shown in Figure 7a, although the total computational time encompasses 25 h, the fitness value decreases rapidly and stabilizes within the first few iterations. The algorithm effectively identifies the high-performance region within the hyperparameter space, delivering a substantial accuracy improvement early on that justifies the computational effort. Figure 7b visualizes the stability of the particle swarm. The decreasing variance in the early stages demonstrates fast convergence, while the intermittent increase in variance reflects the effectiveness of the proposed probabilistic jumping mechanism, which maintains population diversity to prevent premature convergence to local optima. Furthermore, Figure 7c depicts the adaptive trajectory of the learning rate, showing how the algorithm dynamically searches and locks onto the optimal magnitude to balance training speed and stability.
Figure 7.
Convergence of PSO-based hyperparameter optimization for 90-step roll prediction; (a) Evolution of the fitness value (SmoothL1Loss) across PSO iterations. (b) Distribution of particle fitness values across iterations. (c) Adaptive search trajectory of the learning rate during optimization.
After completing the optimization process, Table 2 presents the optimal hyperparameters identified. The PSO algorithm adaptively determined specific configurations for nine distinct forecasting scenarios: Tasks 1–3 correspond to rolling prediction across horizons of 30, 60, and 90 steps, respectively, while Tasks 4–6 and Tasks 7–9 address pitching and heaving motions under the same time steps.
Table 2.
Hyperparameter optimization results for rolling, pitching, and heaving prediction tasks.
To further assess the impact of PSO on training stability, the PSO-optimized hyperparameter configuration for the 90-step rolling prediction task was evaluated under multiple independent training runs with different random seeds. For each configuration, the model was trained repeatedly while keeping all hyperparameters fixed, and the forecasting performance was quantified as the mean ± standard deviation (std) of RMSE, as reported in Table 3.
Table 3.
Prediction performance statistics under different hyperparameter settings.
As shown in Table 3, the performance variance across different runs is small, demonstrating that the hyperparameters identified by PSO lead to stable training behavior rather than relying on favorable random initialization. This stability reinforces the convergence patterns shown in Figure 7b and demonstrates that the PSO-based optimization consistently delivers reliable and repeatable model performance.
In addition to stability evaluation, a local sensitivity analysis was conducted based on the same experimental results summarized in Table 3 to assess the robustness of the PSO-optimized solution. Among the optimized hyperparameters, the learning rate and dropout rate were selected for analysis, as they have the most direct influence on optimization dynamics and generalization performance.
Specifically, each parameter was perturbed by ±20% around its PSO-identified optimal value for the 90-step rolling prediction task, while all other hyperparameters were kept unchanged. The resulting forecasting performance was compared in terms of RMSE. The quantitative results of the sensitivity analysis, together with the stability statistics obtained from repeated runs, are summarized in Table 3. The results show that moderate perturbations lead to only marginal performance degradation, indicating that the identified optimal configuration lies in a relatively flat and stable region of the hyperparameter space rather than at a sharp local optimum.
3. Results and Analysis of Tests
3.1. Ship Simulation and Data Generation
The dataset in this paper was generated based on numerical simulations by using ANSYS-AQWA (version 2022 R2) software. The target vessel was the KCS (KRISO Container Ship) model. The KCS is widely used in international ship hydrodynamics research, and its main parameters are shown in Table 4.
Table 4.
Main parameters of the KCS Ship model.
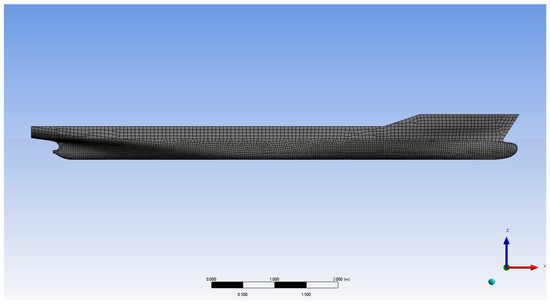
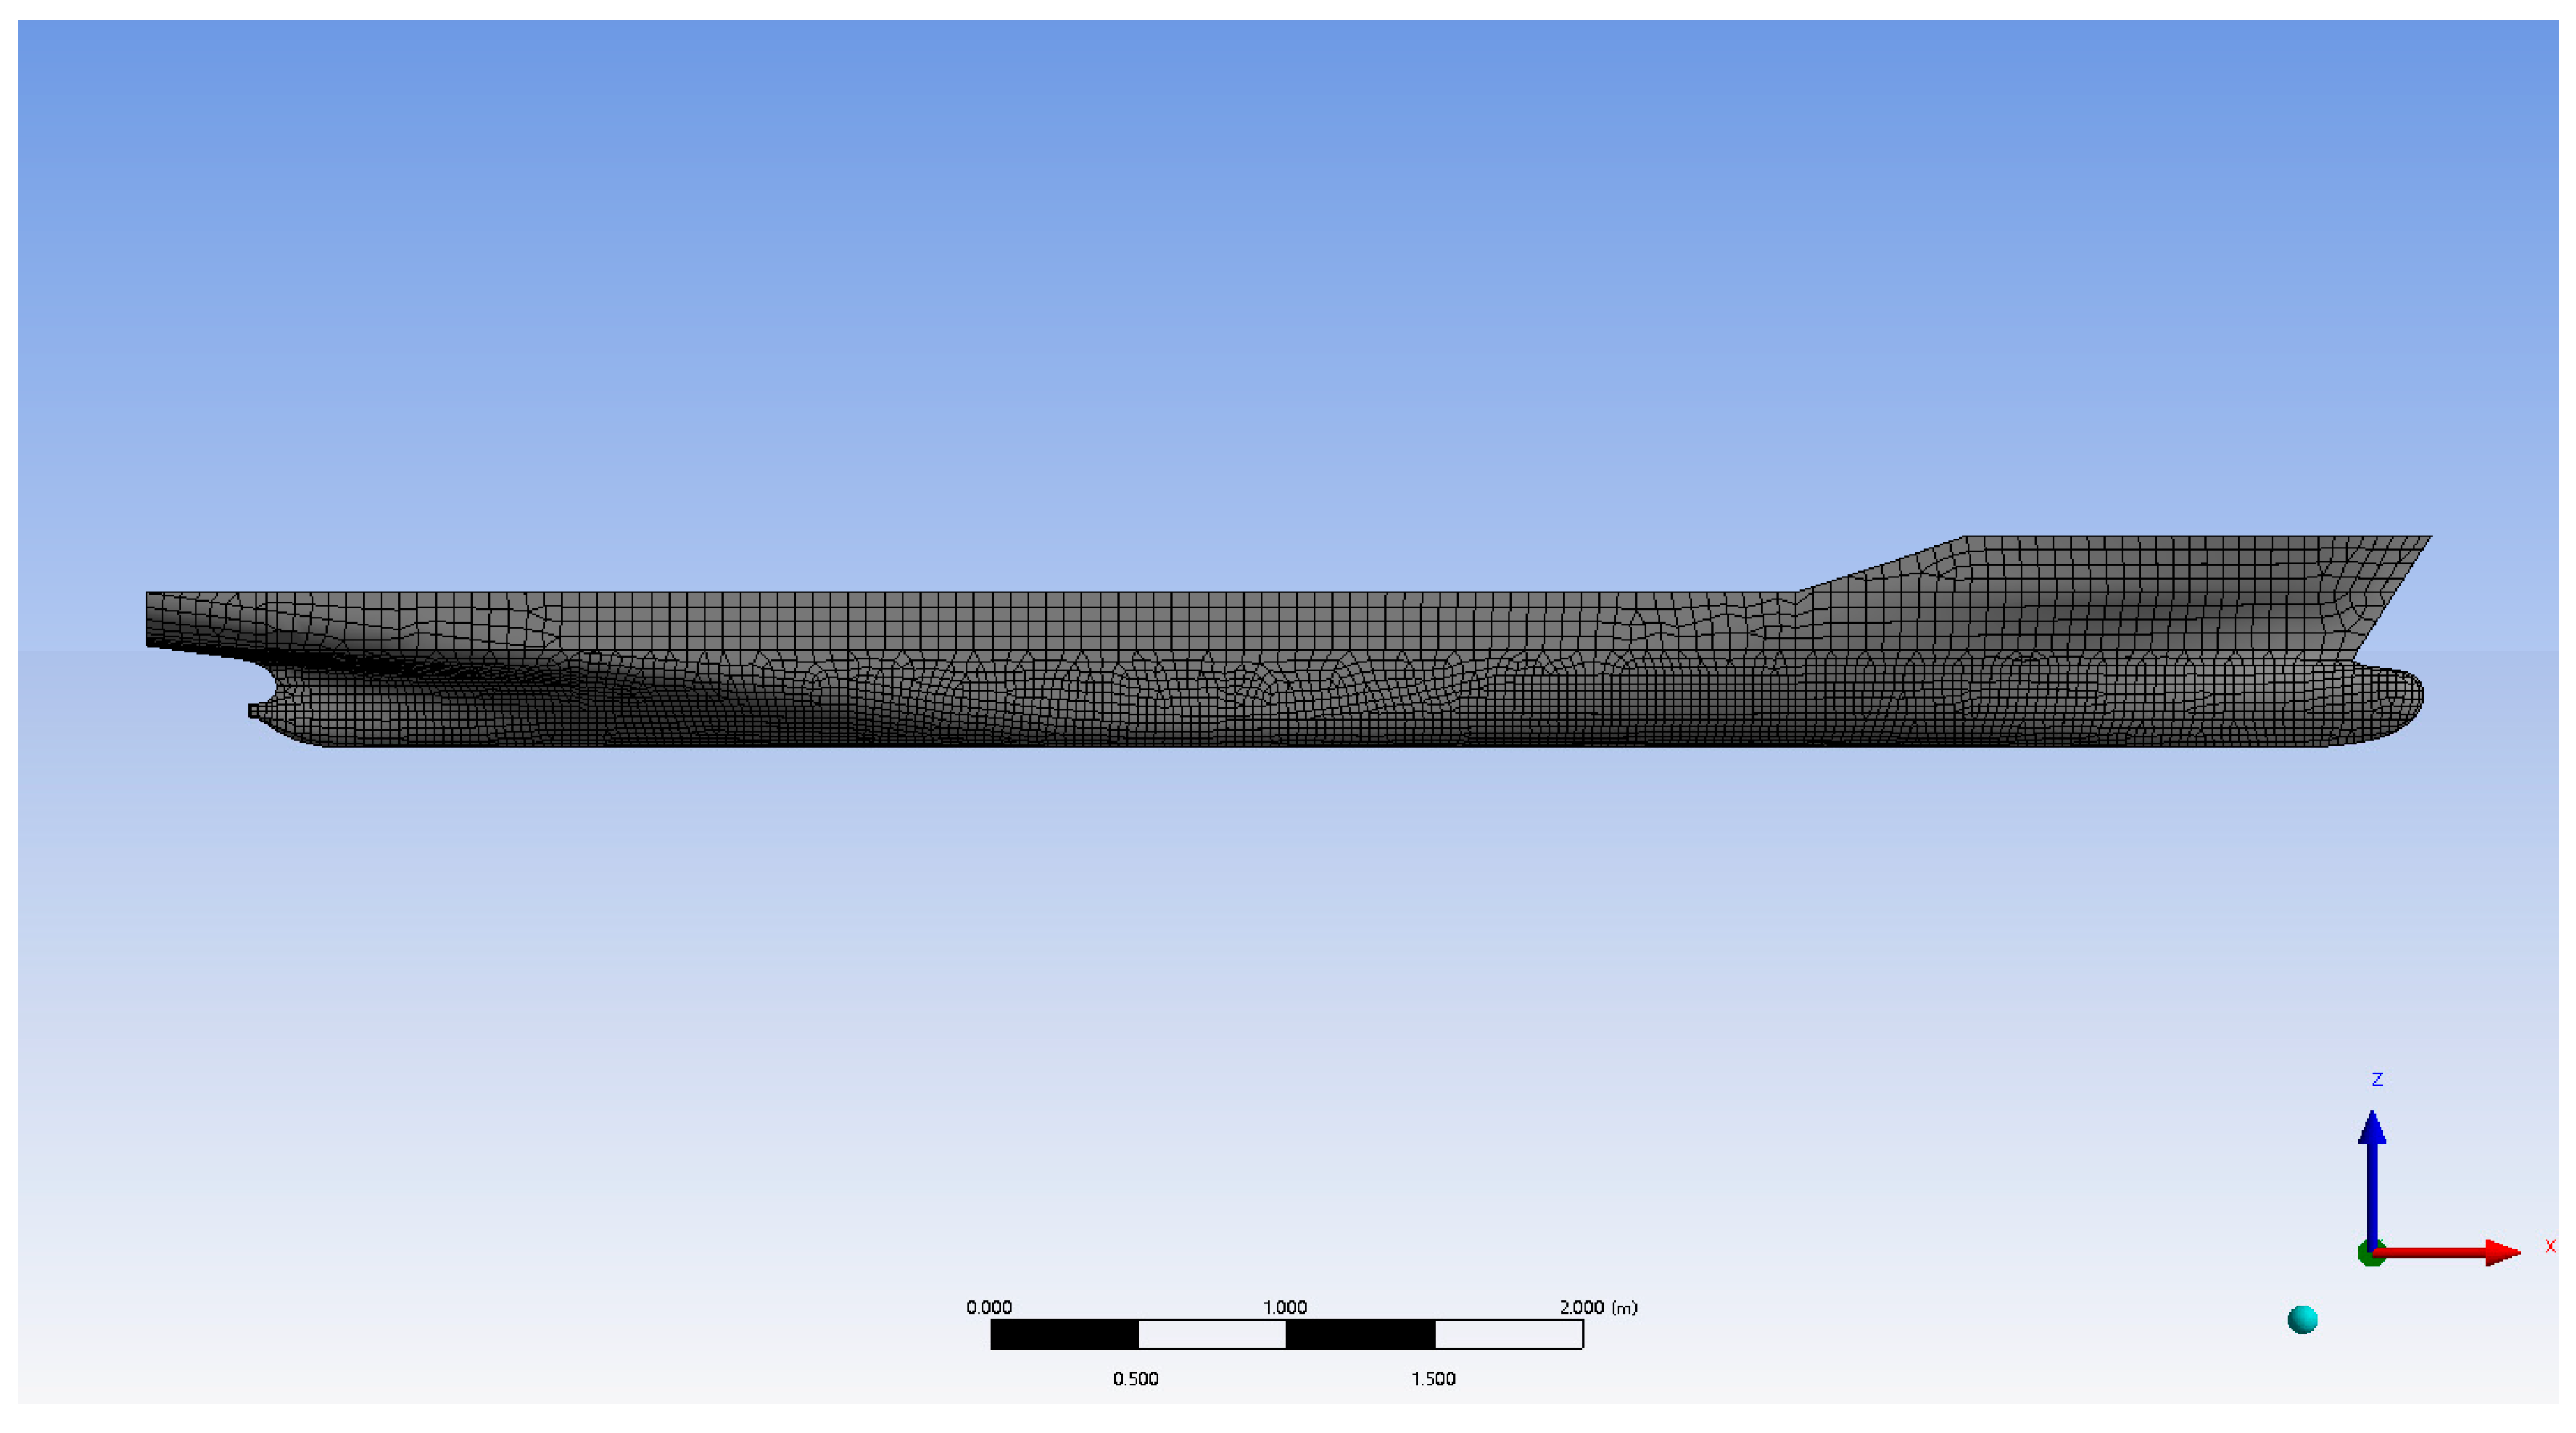
Initially, the KCS model was imported to ANSYS-AQWA software, where the waterline is divided, and the center of gravity, radius of gyration, and mesh settings are configured (as shown in Figure 8). The numerical simulation is governed by the three-dimensional potential flow theory (diffraction/radiation). The fundamental assumptions behind this setup are that the fluid is inviscid, incompressible, and irrotational.
Figure 8.
Simulation experiment model mesh.
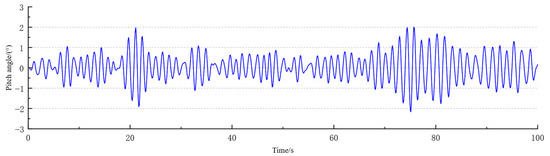
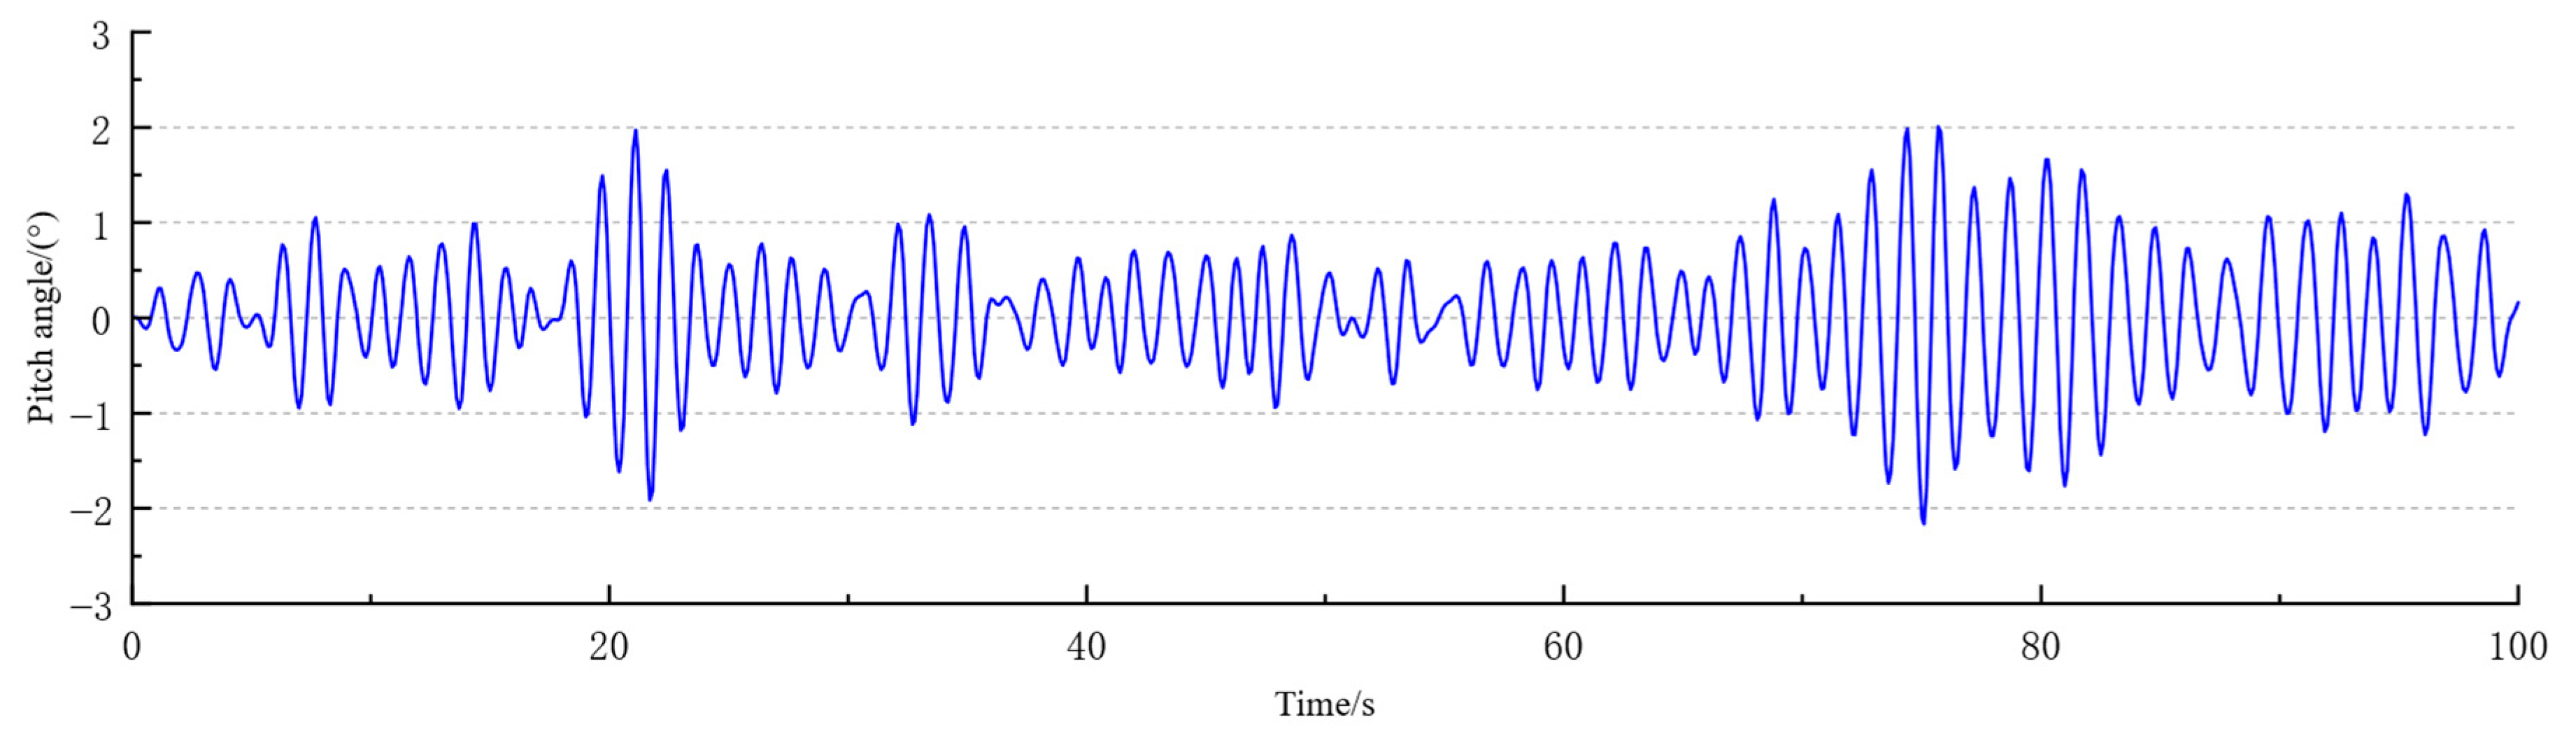
Through hydrostatic calculations, the displacement of the numerical model is found to be 1.6421 m3, with a relative error of 0.42% compared to the design value of 1.6490 m3. Since potential flow theory cannot capture viscous damping effects, an 8% critical damping correction was applied to the roll motion in this paper. Furthermore, to further verify the reliability of the 3D model and the rationality of the settings, we replicated relevant irregular head sea conditions (Hs = 3.833 m, Tz =7.349 s) inspired by the investigation of Nimma et al. in 2018 [47]. The simulated pitch time-domain response curve (as shown in Figure 9) was analyzed and compared. The calculated significant pitch displacement from the simulation data was 1.258°, and it shows close agreement with the 1.278° significant pitch displacement from the cited study of Nimma et al. [47], exhibiting a deviation of only 1.56%. This evidence proved the simulation consistency of results in this study.
Figure 9.
Time histories of pitch.
The ANSYS-AQWA solver employed in this study is based on linear potential flow theory, and nonlinear effects such as time-varying wetted surface and wave breaking are not explicitly modeled. Consequently, it does not fully consider the wetted surface nonlinearity (time-varying wetted surface area) and free-surface nonlinearity (e.g., wave breaking or high-order wave effects). As discussed in the review by Tavakoli et al. [48], linear models differ from nonlinear models in capturing these complex fluid–structure interactions, which may introduce discrepancies under extreme sea states. However, for the operational conditions considered in this research (Sea State 3 and 4), the linear approach provides a computationally efficient and sufficiently accurate approximation for developing the forecasting model.
The simulations adopt irregular waves to more realistically simulate the marine environment. The wave energy spectrum uses the JONSWAP spectrum, which is suitable for describing developing wind waves in a limited fetch. The peak enhancement factor is set to 3.3, indicating that wave energy is concentrated around the peak frequency, exhibiting a significantly sharp-peaked shape. The simulation of wave directionality was achieved through a directional distribution function, employing a short-crested wave model. The main wave direction was 30°, and a 2nd power cosine function was used for directional distribution to simulate short-crested waves, with a total distribution angle of 180°. For numerical calculation purposes, this directional spectrum was discretized into 7 directional sub-spectra for superposition. In the frequency domain, the calculation frequency range for wave energy was defined from 0.1 Hz to 2.0 Hz. This frequency interval was discretized into 70 equally spaced frequency components to ensure sufficient resolution of the wave spectrum. The phase seed generation method for random waves was controlled by the ANSYS-AQWA solver to ensure reproducibility of simulation results under a specific seed.
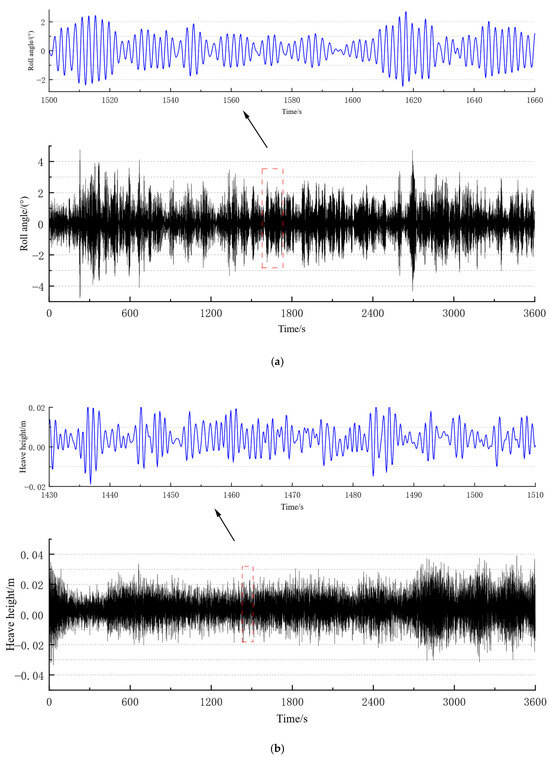
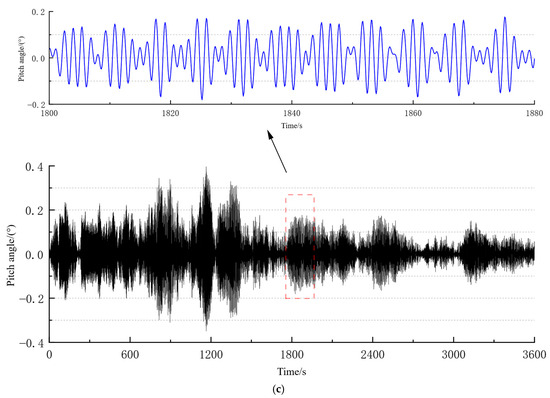
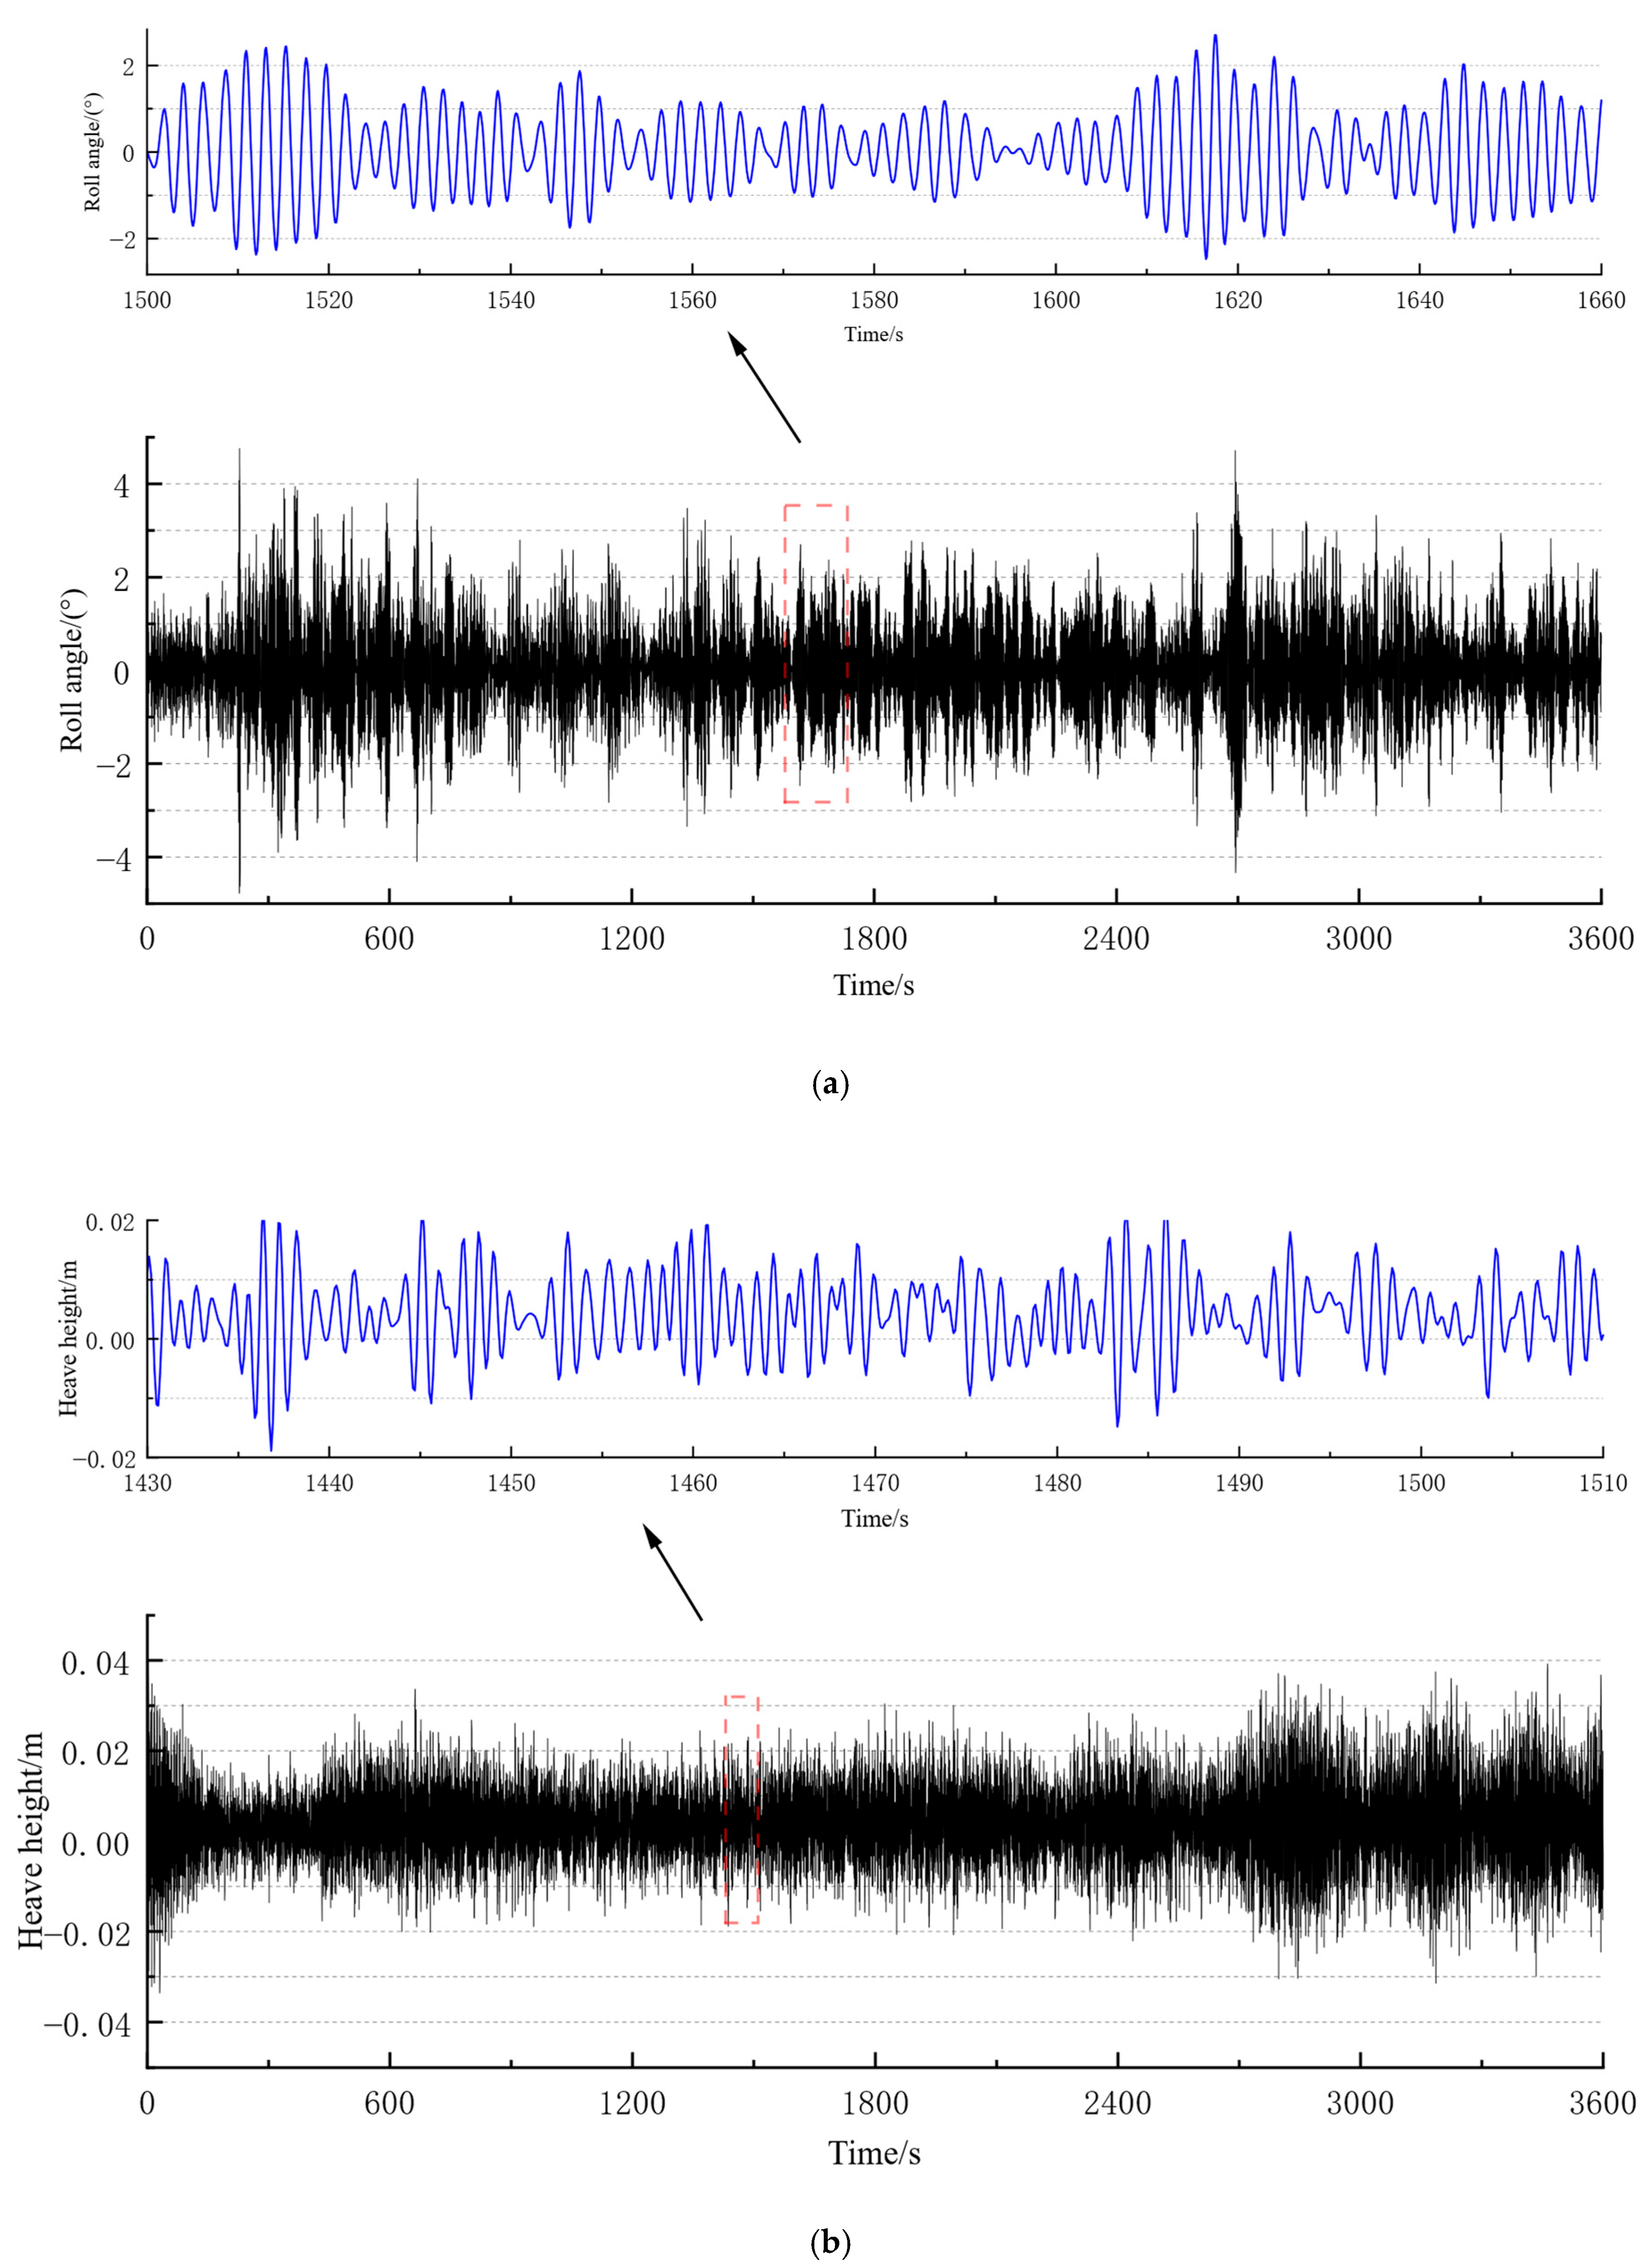
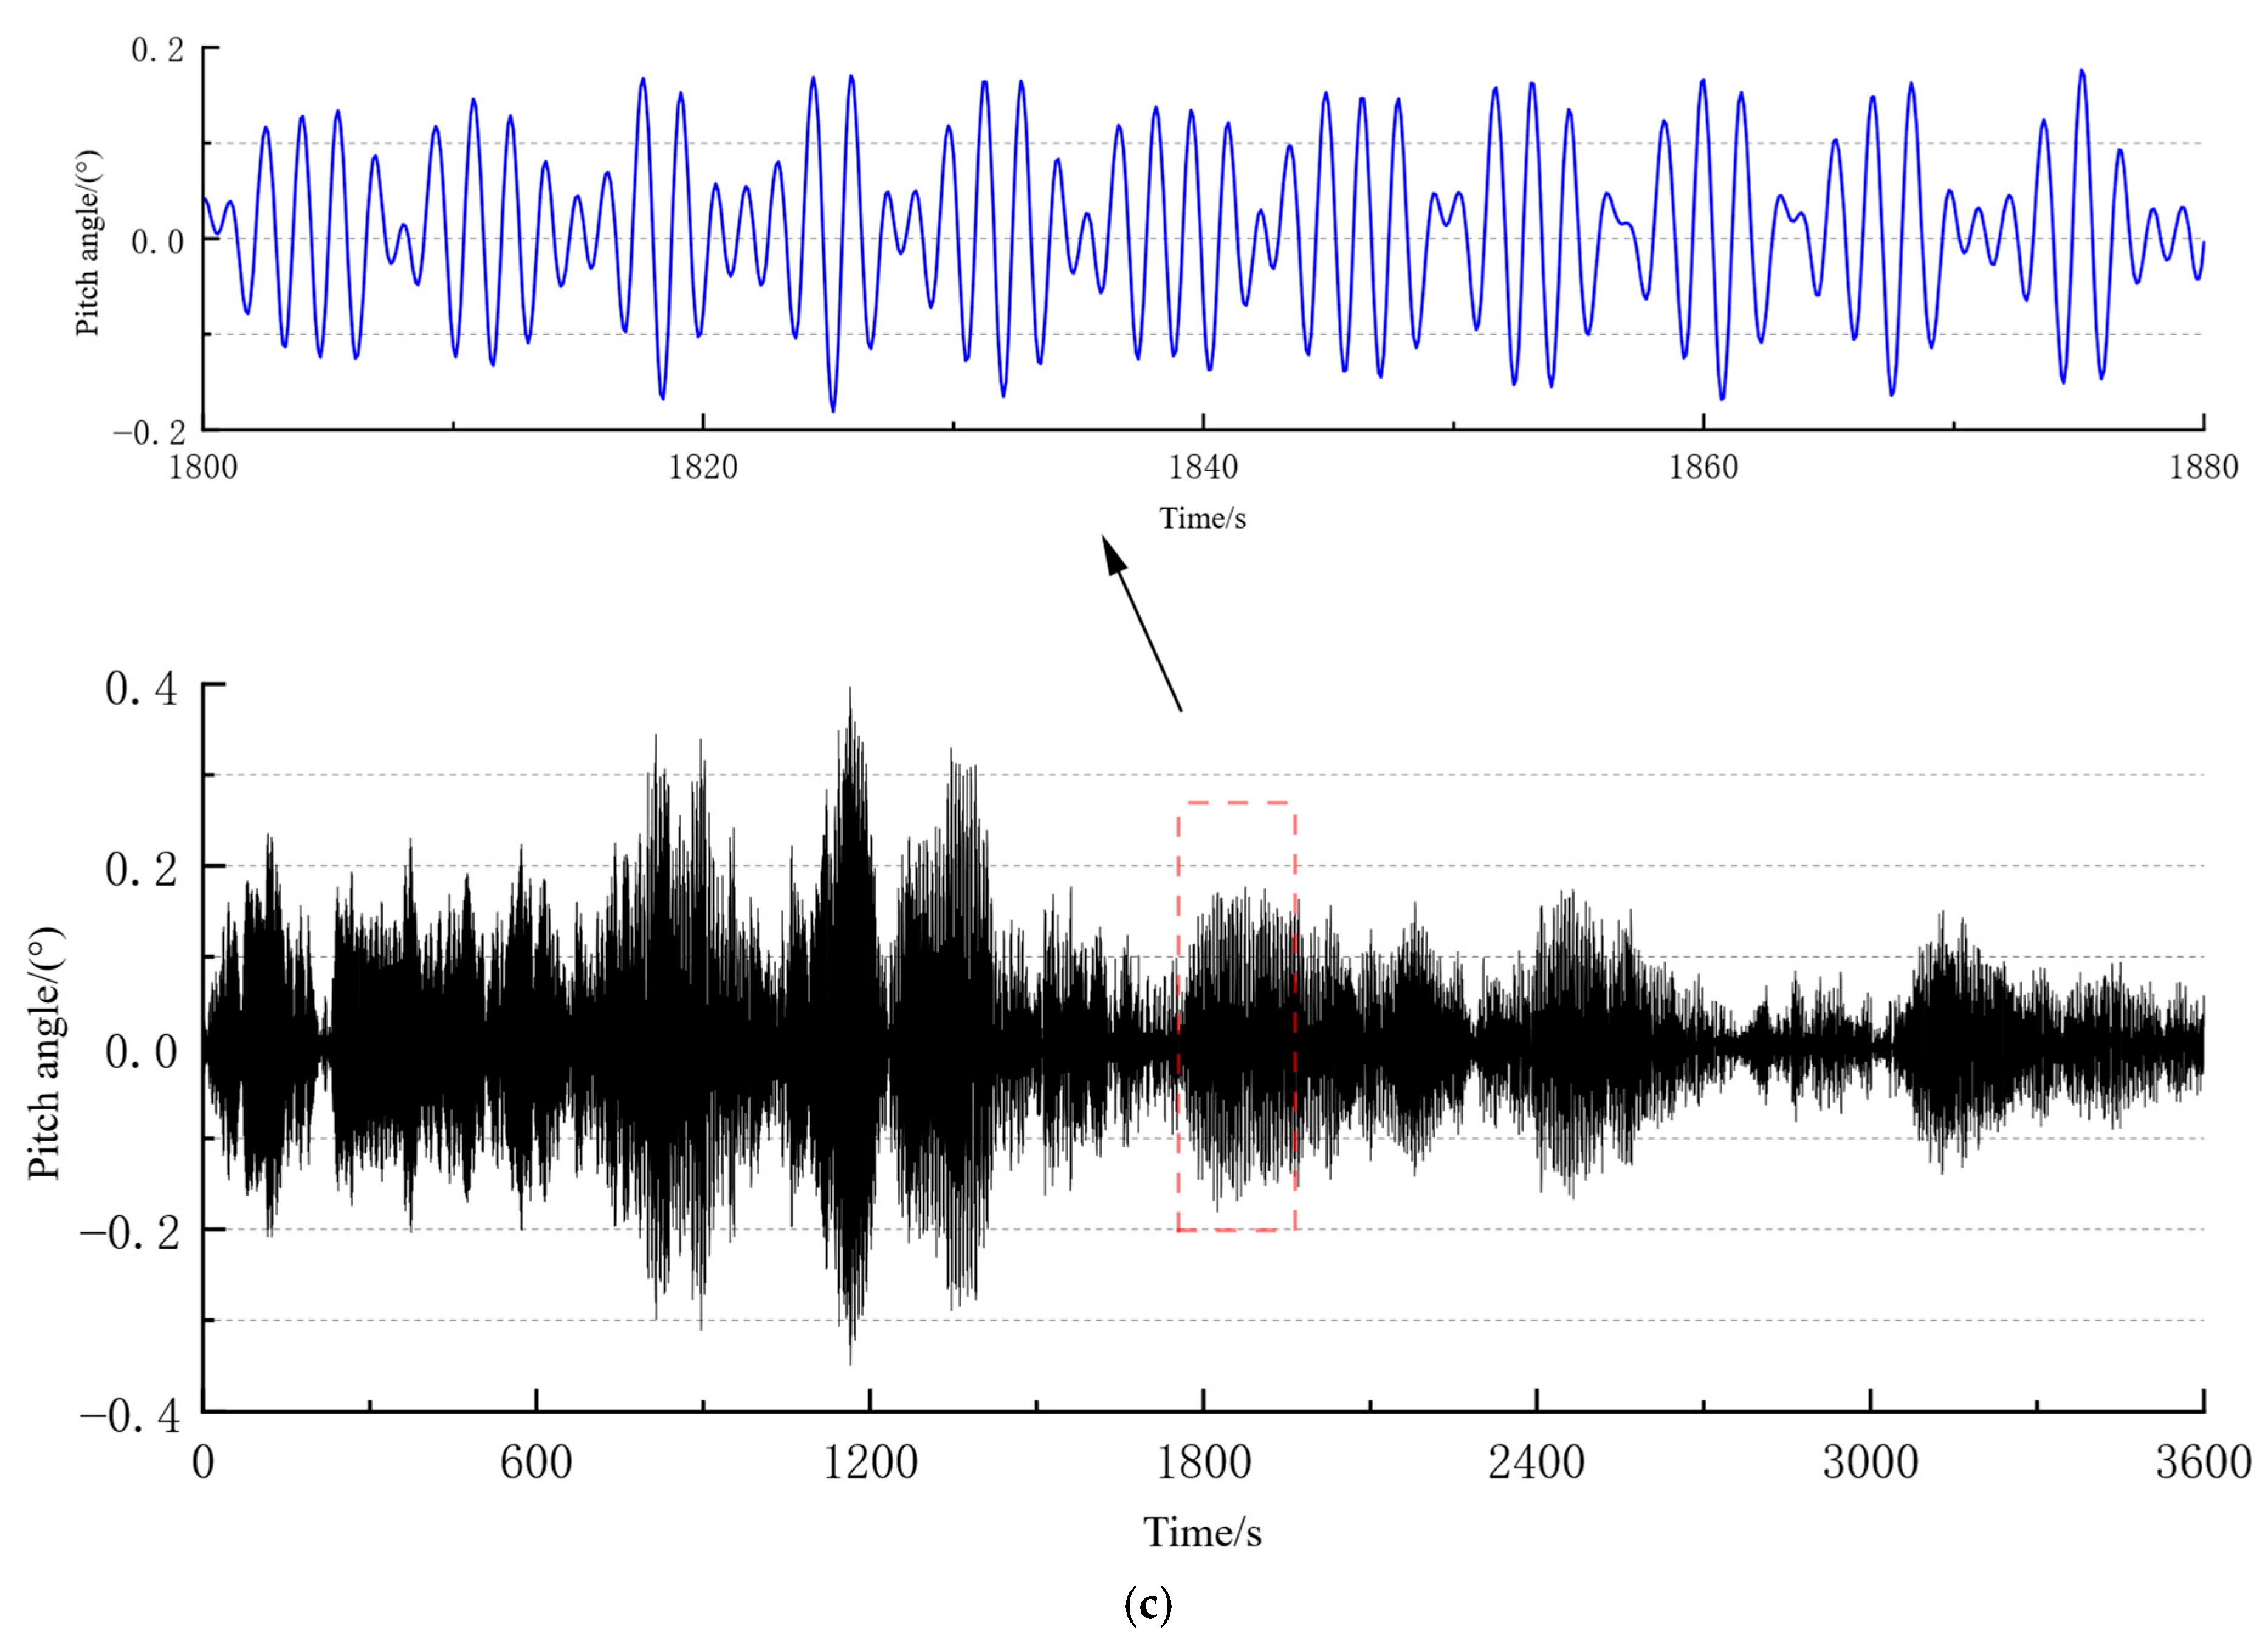
A combination of three forward speeds (corresponding Froude numbers are 0.24, 0.26, and 0.28) and five distinct major wave heights was selected to form 15 sets of operating conditions. The detailed wave parameters are listed in Table 5. The selection of these parameters balances operational representativeness with numerical validity: the wave heights corresponded to typical Sea States 3 through 4, while the wave frequencies were calibrated to maintain a constant moderate wave steepness. This approach guarantees compliance with the linear potential flow assumptions built into the ANSYS-AQWA solver. For deep water, the wavenumber associated with the peak frequency was obtained from the linear dispersion relation , and the wave steepness was computed as . As shown in Table 5, the calculated steepness remains approximately 0.099 across all cases. This steepness implies the presence of weakly nonlinear effects; it remains well below the theoretical breaking limit. Consequently, the linear potential flow assumption was adopted as a practical engineering approximation for the operational conditions in this study, balancing theoretical limitations with the computational efficiency required for dataset generation. The simulation duration for each condition was 3600 s, and the sampling frequency was set to 10 Hz. Figure 10 illustrates representative time histories of roll, pitch, and heave motions under a selected operating condition.
Table 5.
Wave parameters.
Figure 10.
Ship motion response curves under different operating conditions: (a) roll response for Fr = 0.28, Hs = 2.5 m; (b) heave response for Fr = 0.26, Hs = 2 m; (c) pitch response for Fr = 0.28, Hs = 1 m.
3.2. Setup and Evaluation of Experiment
To comprehensively evaluate the performance of the proposed hybrid model (LT) and the particle swarm optimization-enhanced hybrid model (P-LT) in time series forecasting tasks, this study designs a multi-level comparative experimental framework. Representative baseline models with different architectural characteristics are considered for comparison, including a two-layer stacked LSTM model, a two-layer standard Transformer model, and a temporal convolutional network (TCN) composed of four stacked temporal convolutional blocks. All baseline models adopt the same output layer design as the proposed LT and P-LT models, with final predictions generated through fully connected networks, thereby ensuring a fair comparison by eliminating the influence of output layer differences.
To ensure the fairness of experiments and the comparability of results, all models participating in the comparison adopted completely consistent training parameter configurations. The detailed settings, including optimizer choice, learning rate schedule, and stopping criteria, are summarized in Table 6.
Table 6.
Unified training parameters and experimental settings.
The experiments were conducted on a high-performance computing platform to ensure computational efficiency. The detailed hardware specifications, software environment, and the total training time consumed by each of the four models are listed in Table 7.
Table 7.
The specification of computers and training costs for the four models.
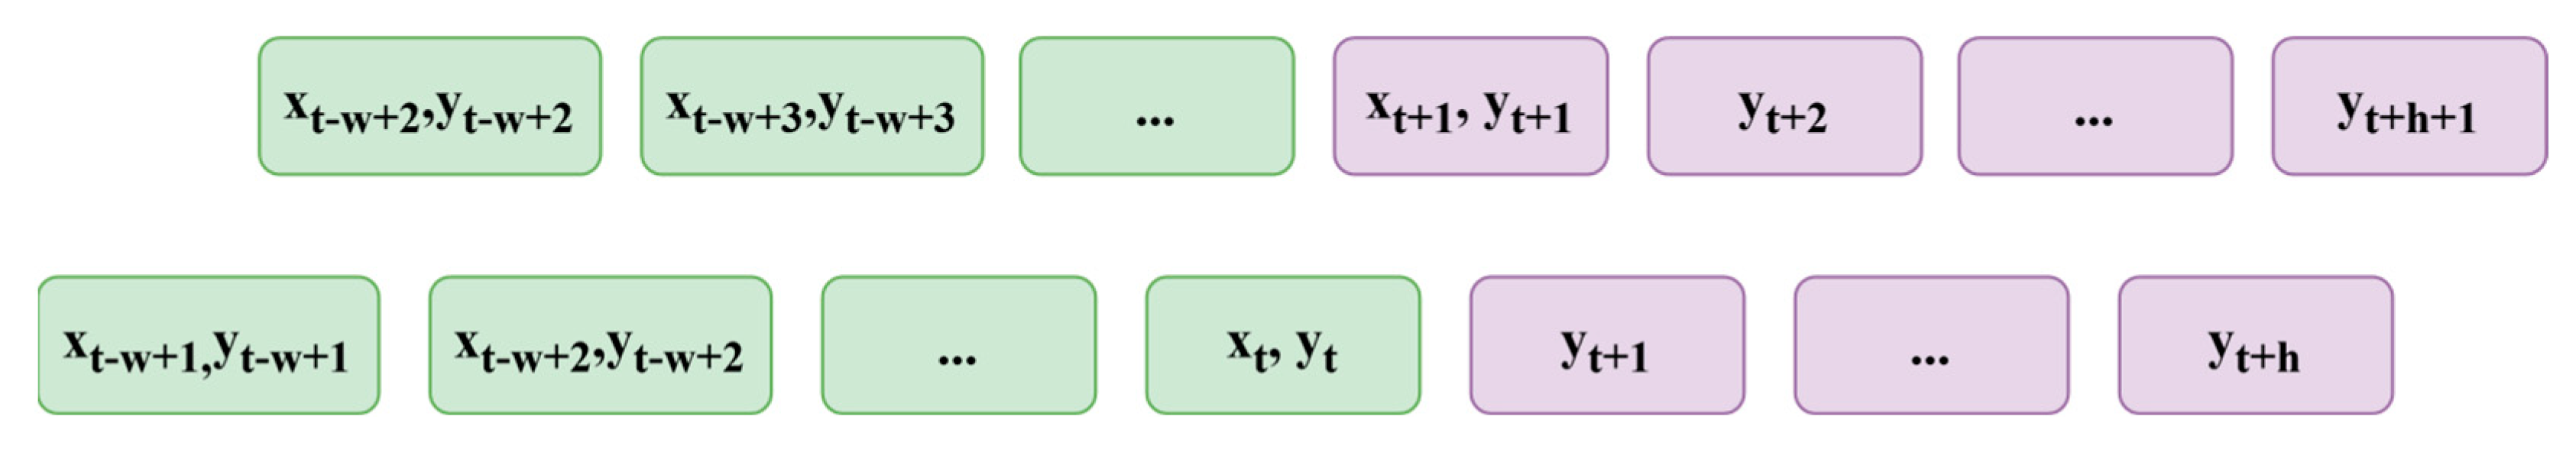
This study takes multi-step ship motion forecasting as the target task, dividing the ship motion time series dataset into a training set, validation set, and testing set using an 8:1:1 ratio. To eliminate the impact of data scale differences on model training, the StandardScaler standardization method was employed to process all datasets, and a sliding window mechanism (window structure shown in Figure 11) was adopted to construct model input sequences with a historical window length set to 60. To comprehensively verify the generalization capability of the models, a comparative analysis of prediction performance was conducted for three key ship motion dimensions—roll, pitch, and heave—at multiple steps (t + 30, t + 60, and t + 90).
Figure 11.
Sliding window method.
This investigation involves three evaluation methods from various viewpoints. The Root Mean Square Error (RMSE) was adopted, while Mean Absolute Error (MAE) and Normalized Root Mean Square Error (NRMSE) were used as auxiliary evaluation. NRMSE was calculated by dividing RMSE by the data range, providing a scale-independent measure of prediction accuracy in this study.
Considering the presence of fundamental outliers and sudden motion patterns in ship motion data under mixed sea states, this study adopts the Smooth L1 loss function for training. Its mathematical expression is presented in Equation (8).
where is the true value, is the predicted value, is the absolute residual, and is an adjustable threshold (the default value of 1.0 is used in this paper).
Unlike Mean Squared Error (MSE), which imposes a quadratic penalty on all residuals and is thus overly sensitive to extreme values, the Smooth L1 loss function cleverly combines the advantages of both MSE and MAE: for smaller errors, it behaves like MSE with a quadratic penalty, enabling refined optimization, whereas for larger errors, it transitions to a linear penalty like MAE, thereby offering robustness against outliers. This specific characteristic of Smooth L1 loss is particularly well-suited for ship motion prediction scenarios, where sudden roll deviations occurring under harsh sea conditions should not disproportionately dominate the training process at the expense of prediction accuracy for more common operating conditions.
The evaluation metrics RMSE and MAE are defined in Equations (9) and (10):
3.3. Results and Analysis of Forecasting
3.3.1. Statistical Significance Analysis
Performance metrics (to be discussed in Section 3.3.2) offer a quantitative basis for comparing models, but it is critical to confirm that the improvements seen in the proposed hybrid model reflect true differences rather than random variations in the test data. To address this, a paired bootstrap resampling procedure was employed to estimate the uncertainty of the performance differences and construct confidence intervals (CIs).
Unlike parametric tests that depend on strict normality assumptions, the bootstrap method provides a flexible, non-parametric alternative for hypothesis testing. Given that the accumulation of prediction error is most critical at long horizons, we constructed a comparative test set specifically for the 90-step prediction scenario. Let and denote the two models under comparison (e.g., LSTM vs. LT, or LT vs. P-LT). This paired test set, denoted as , is formally defined as Equation (11):
where represents the total number of samples in the test set, is the observed ground truth, and and denote the predicted values given by models and , respectively. To assess the statistical significance of the performance difference, we generated bootstrap samples, denoted as , by drawing instances from with replacement. For each iteration , the difference in Root Mean Square Error (RMSE) is computed using Equation (12):
where and correspond to the predictions of model and model in the -th bootstrap sample. This process yields an empirical distribution of the performance differential . A negative mean value of , combined with a 95% confidence interval that does not include zero, indicates that the proposed model achieves a statistically significant reduction in RMSE compared to the reference model.
The quantitative outcomes of the paired bootstrap test are summarized in Table 8. Here, the mean difference represents the average reduction in RMSE achieved by the proposed hybrid model compared to the base compared to the baseline model.
Table 8.
Paired bootstrap test results for statistical significance of prediction performance differences.
3.3.2. Time-Domain Analysis
The evaluation results of roll forecasting are shown in Table 9. At t + 30, the TCN model actually performs well—its RMSE of 0.1300 beats both the LSTM and Transformer. However, as the forecast horizon extends, the accuracy of all single models drops sharply. Looking at the numbers, the P-LT model’s error jumped by nearly 58% (rising from 0.1141 to 0.1802) between t + 30 and t + 90. This increase is much steeper than what we see in pitch (46.44%) or heave (45.71%). These results confirm that the transverse plane is particularly sensitive to cumulative errors, mostly due to lightly damped resonance.
Table 9.
Performance metrics of each model for different prediction spaces in roll prediction.
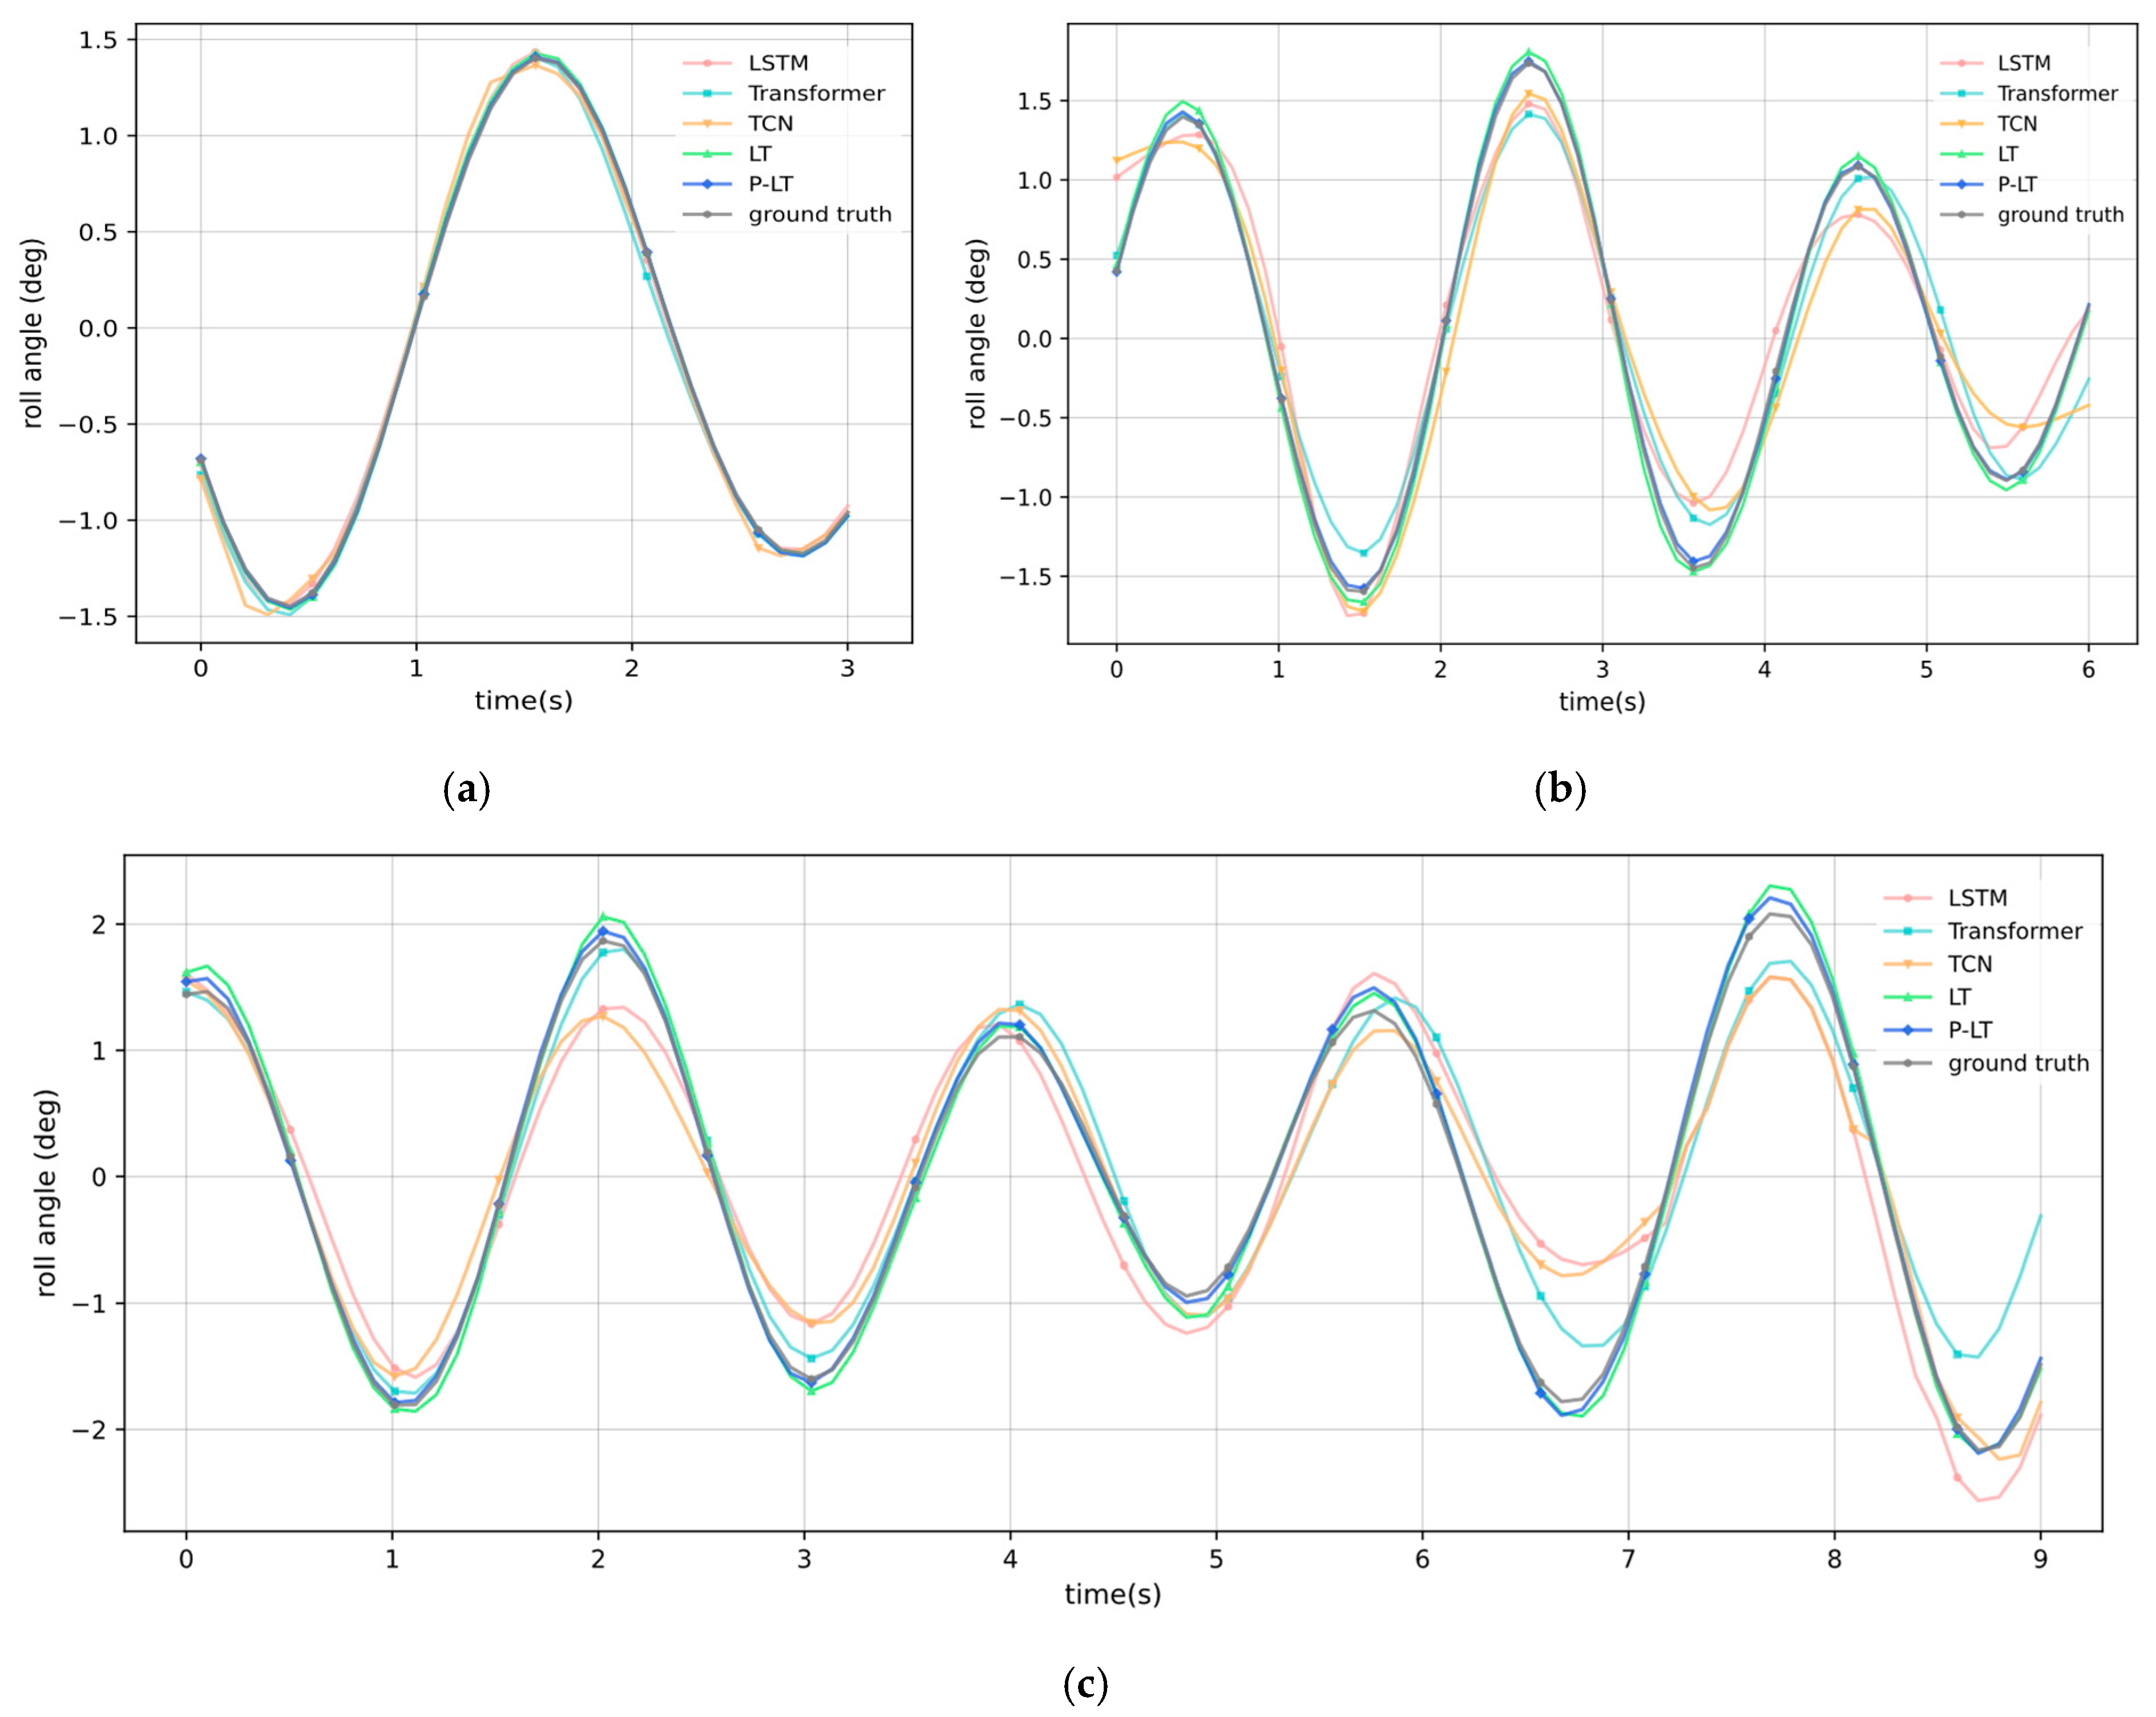
Figure 12 clearly illustrates that the models differ markedly in their predictive accuracy. While short-term models appear consistent across the board (Figure 12a), the single-architecture models (Transformer, LSTM, and TCN) show marked deterioration when predicting extreme values over longer horizons (Figure 12b,c). For example, at the dominant peak near , in Figure 12c, single-architecture models underestimate roll amplitude by approximately 24% (). This suggests a tendency to converge towards an overdamped response to minimize global loss. The P-LT model, on the other hand, effectively preserves high-amplitude peaks and corrects phase misalignment. It notably reduces the lag seen in the LSTM during zero-crossing at approximately . The P-LT model’s better performance results from its hybrid encoder–decoder architecture. The LSTM encoder effectively models the vessel’s short-term inertial dynamics, while the Transformer decoder applies self-attention to capture the complete temporal context within the observation window. This contextual attention mechanism acts as a stabilizer, enforcing the resonant characteristics of roll motion and preventing the signal energy dissipation observed in single models.
Figure 12.
Results of roll prediction and comparative experiments: (a) 30-step roll prediction result. (b) 60-step roll prediction result. (c) 90-step roll prediction result.
Table 10 presents the results for pitch motion forecasting. The vessel is subject to strong longitudinal hydrostatic restoring forces (high hydrostatic stiffness). This physical constraint restricts error divergence more than in roll motion, leading to a more moderate error growth of 46.44% for the P-LT model. Single-architecture models, however, fail to track these restoring dynamics consistently, resulting in predictive instability.
Table 10.
Performance metrics of each model for different prediction spaces in pitch.
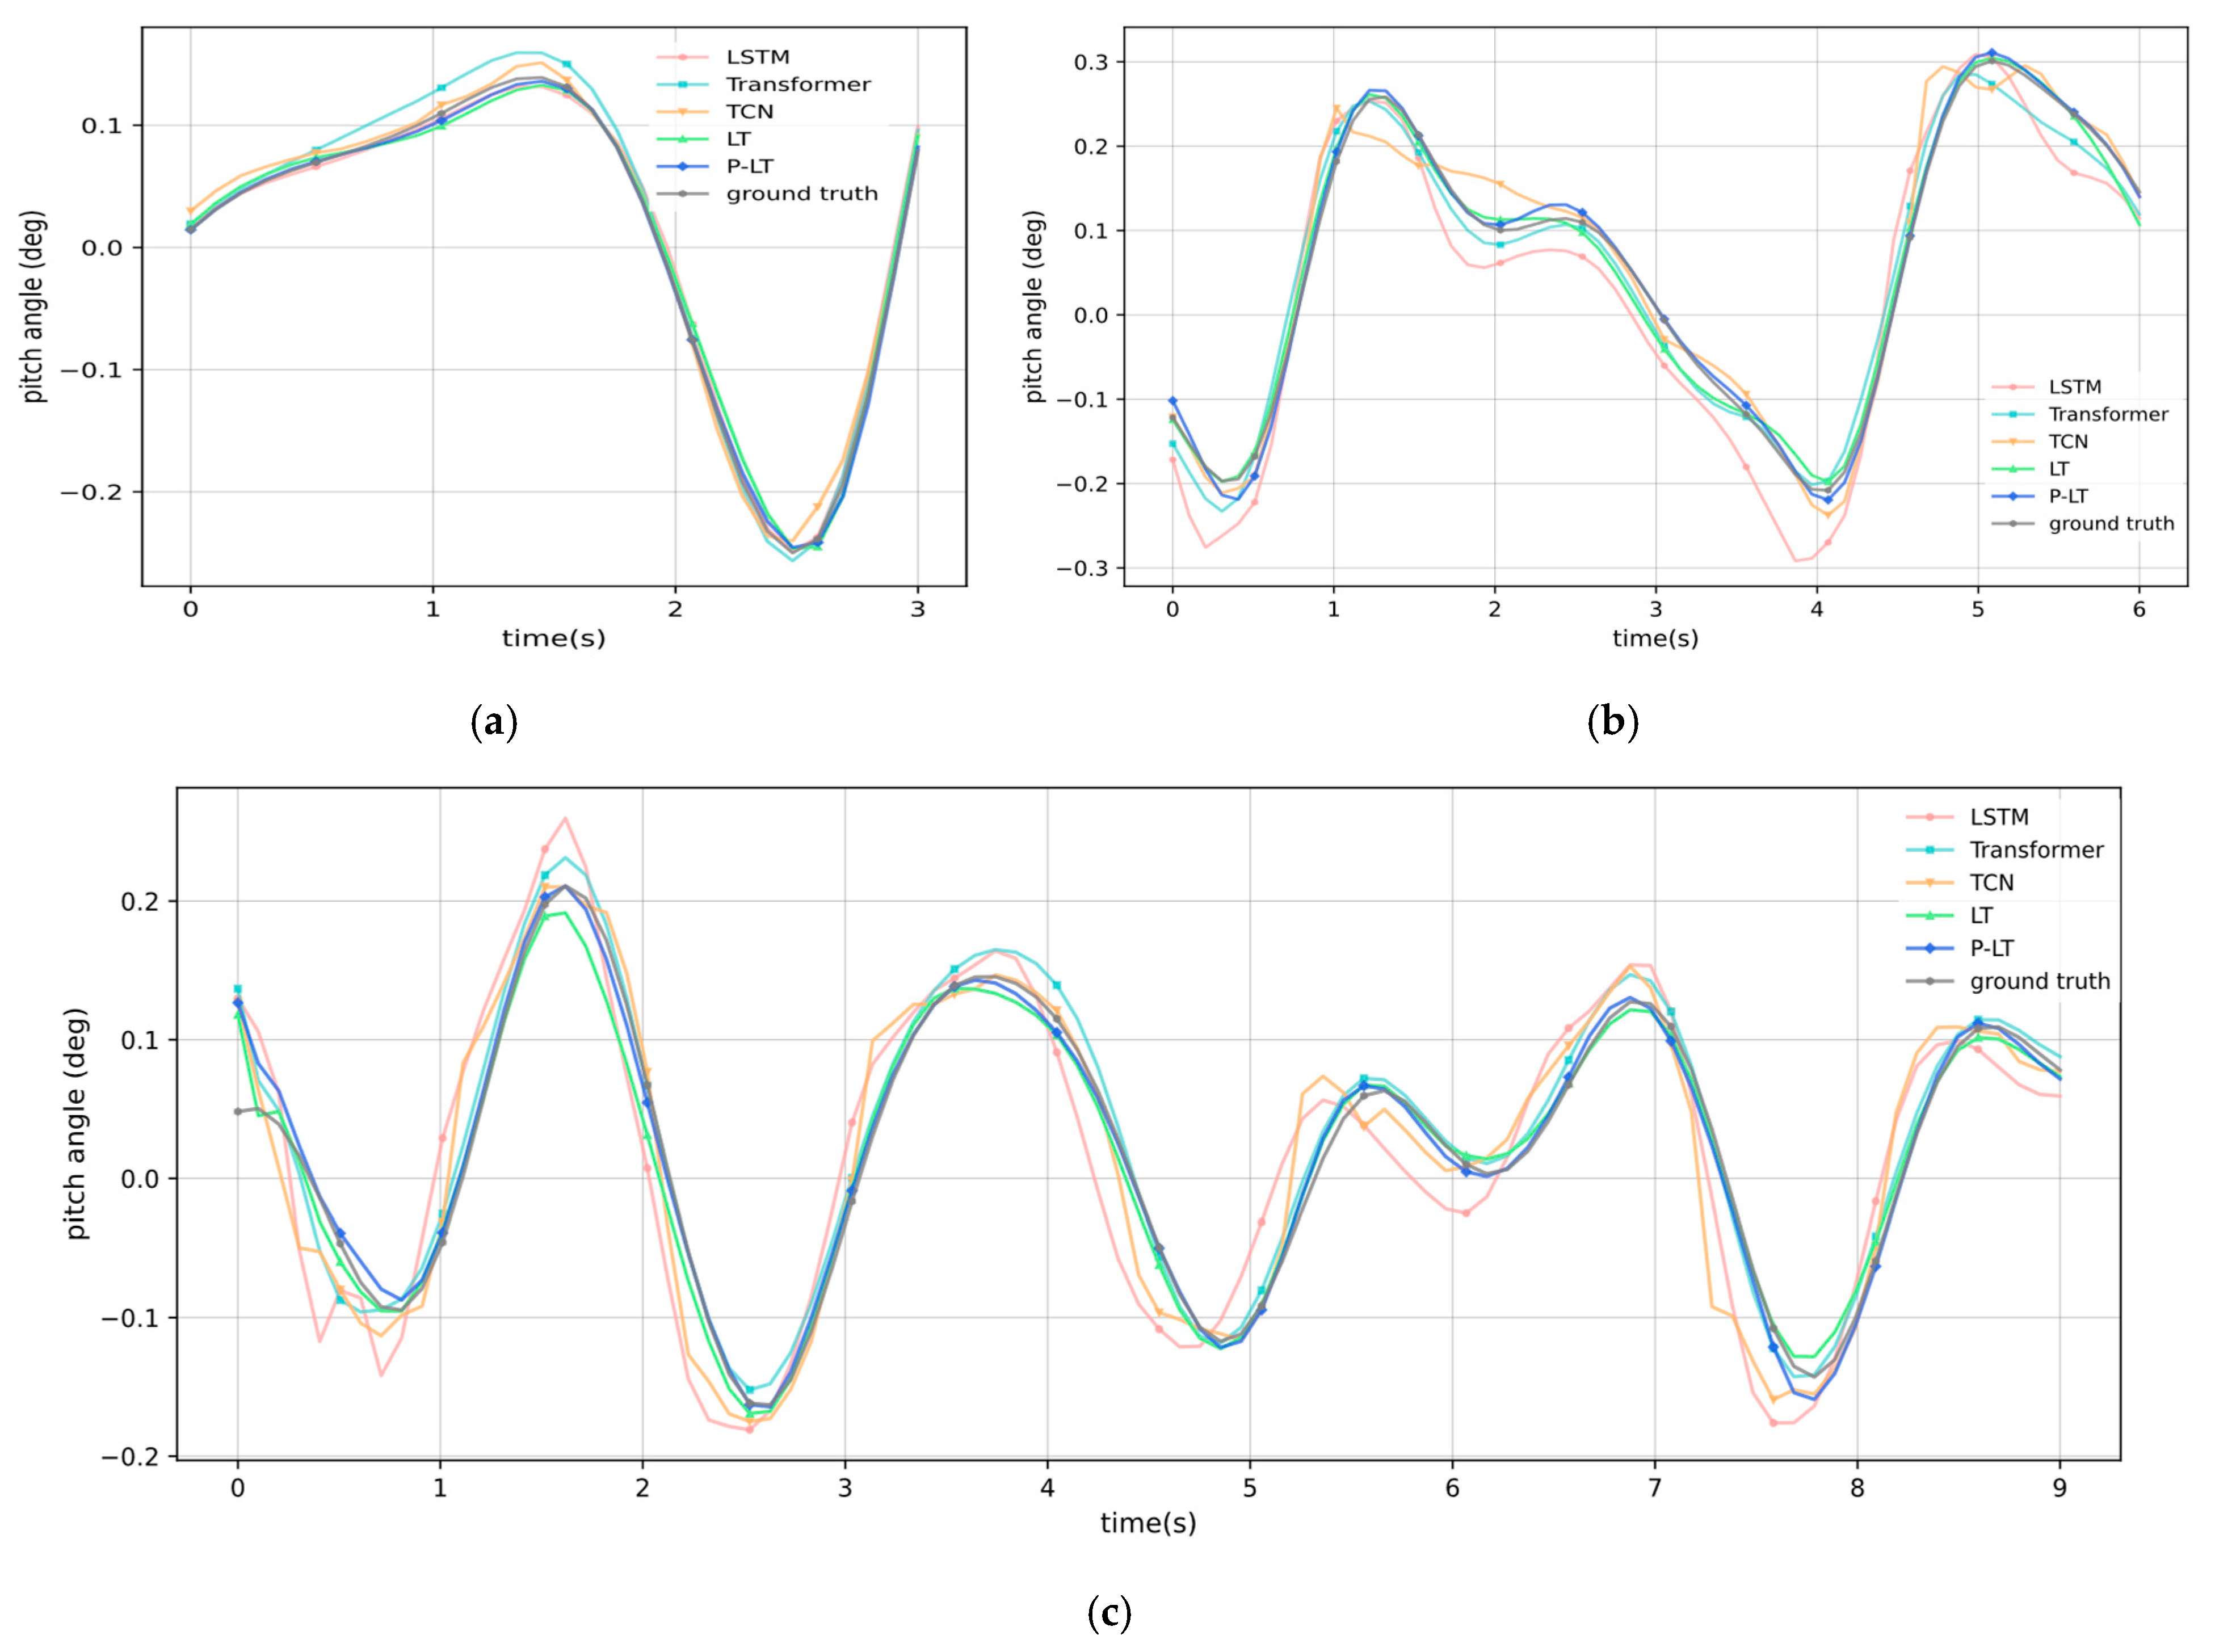
Figure 13 illustrates clear differences in prediction behaviors. The standalone LSTM displays severe instability (Figure 13b,c) and produces spurious non-physical oscillations. It even exaggerates pitch angle by 38% at the troughs. This error happens because the LSTM lacks verification of the sequence-level temporal context. The P-LT model, by contrast, uses a cross-attention mechanism in its decoder. The Transformer decoder reviews the full encoded history to identify the dominant wave-frequency trajectory. This capability keeps the P-LT model synchronized with the ground truth, preventing the anomalous amplitude fluctuations often seen in pure RNN models.
Figure 13.
Results of pitch prediction and comparative experiments: (a) 30-step pitch prediction result. (b) 60-step pitch prediction result. (c) 90-step pitch prediction result.
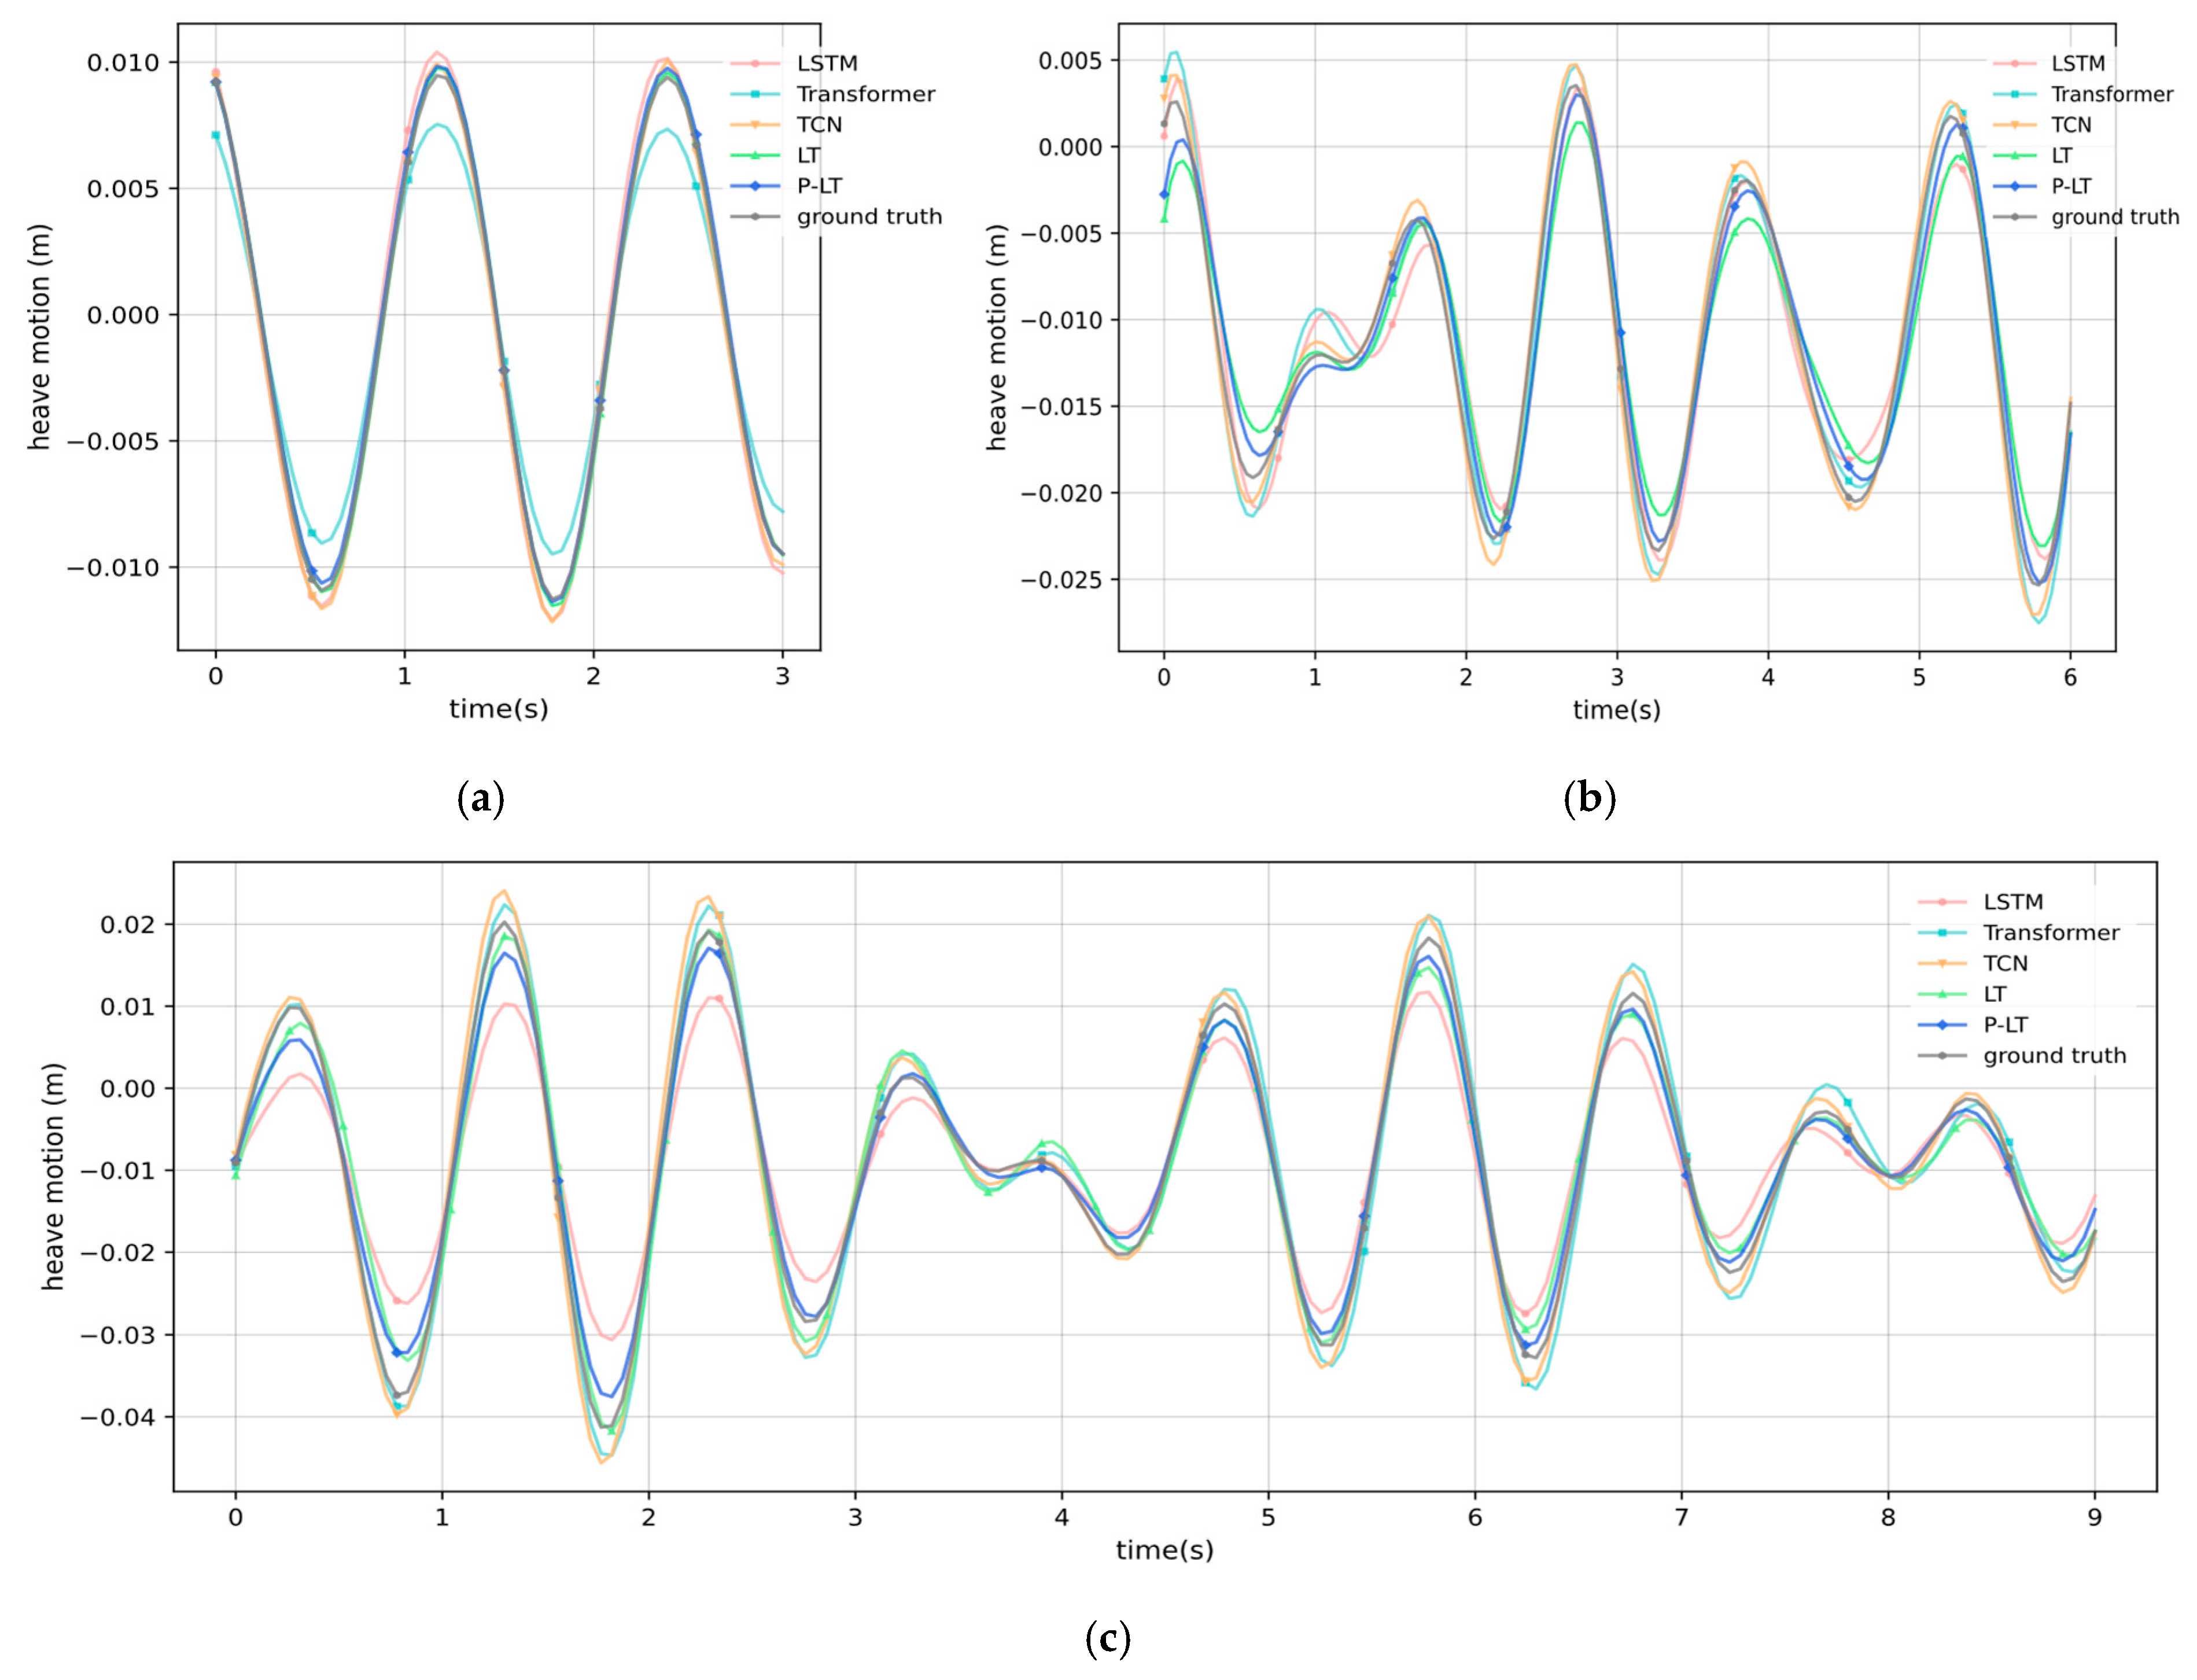
Table 11 presents the results for heave motion, which confirm the strong hydrodynamic coupling with pitch. Similar to the longitudinal dynamics seen in the pitch analysis, the P-LT model keeps error growth controlled at 45.71%. This indicates greater stability compared to the roll scenario. Among the single models, TCN reaches the lowest RMSE at t + 30 (0.0076), yet it still falls short of the hybrid P-LT model. Standalone models generally struggle with complex coupled dynamics over longer horizons, failing to maintain the consistency needed for the heave-pitch interaction.
Table 11.
Performance metrics of each model for different prediction spaces in the heave prediction.
As shown in Figure 14, standalone architectures have clear limitations. The LSTM underestimates amplitude by 45% and does not accurately capture the energy transfer resulting from coupling. The hybrid P-LT model achieves success by integrating stepwise energetic evolution with sequence-level contextual analysis. The LSTM encoder processes the coupled states in sequence, actively maintaining the phase relationships that define hydrodynamic coupling. The Transformer decoder then gathers this information to predict future steps. This approach integrates the LSTM to capture instantaneous inertial dynamics with the Transformer’s ability to model overall patterns, ensuring the predicted trajectory effectively suppresses numerical damping while avoiding inconsistencies in kinematic logic.
Figure 14.
Results of the heave prediction and comparative experiments: (a) 30-step heave prediction result. (b) 60-step heave prediction result. (c) 90-step heave prediction result.
3.3.3. Frequency-Domain Analysis
Time-domain error metrics (e.g., RMSE, MAE) quantify prediction accuracy but do not explicitly assess whether the model captures the oscillatory characteristics and resonance behavior of ship motions. To evaluate the reproduction of spectral content, we conducted a frequency-domain analysis using the Fast Fourier Transform (FFT). For a time series signal , the frequency spectrum is computed as follows:
This analysis focuses on roll and pitch motions, as these rotational degrees of freedom are most susceptible to resonance and are essential for seakeeping and stability assessment. Heave was excluded due to its predominantly wave-frequency-driven response and simpler resonance characteristics.
We focused on the 90-step prediction, the most challenging case with the greatest error accumulation; spectral fidelity here implies robustness at shorter horizons (30 and 60 steps). The proposed P-LT model was compared to the Transformer.
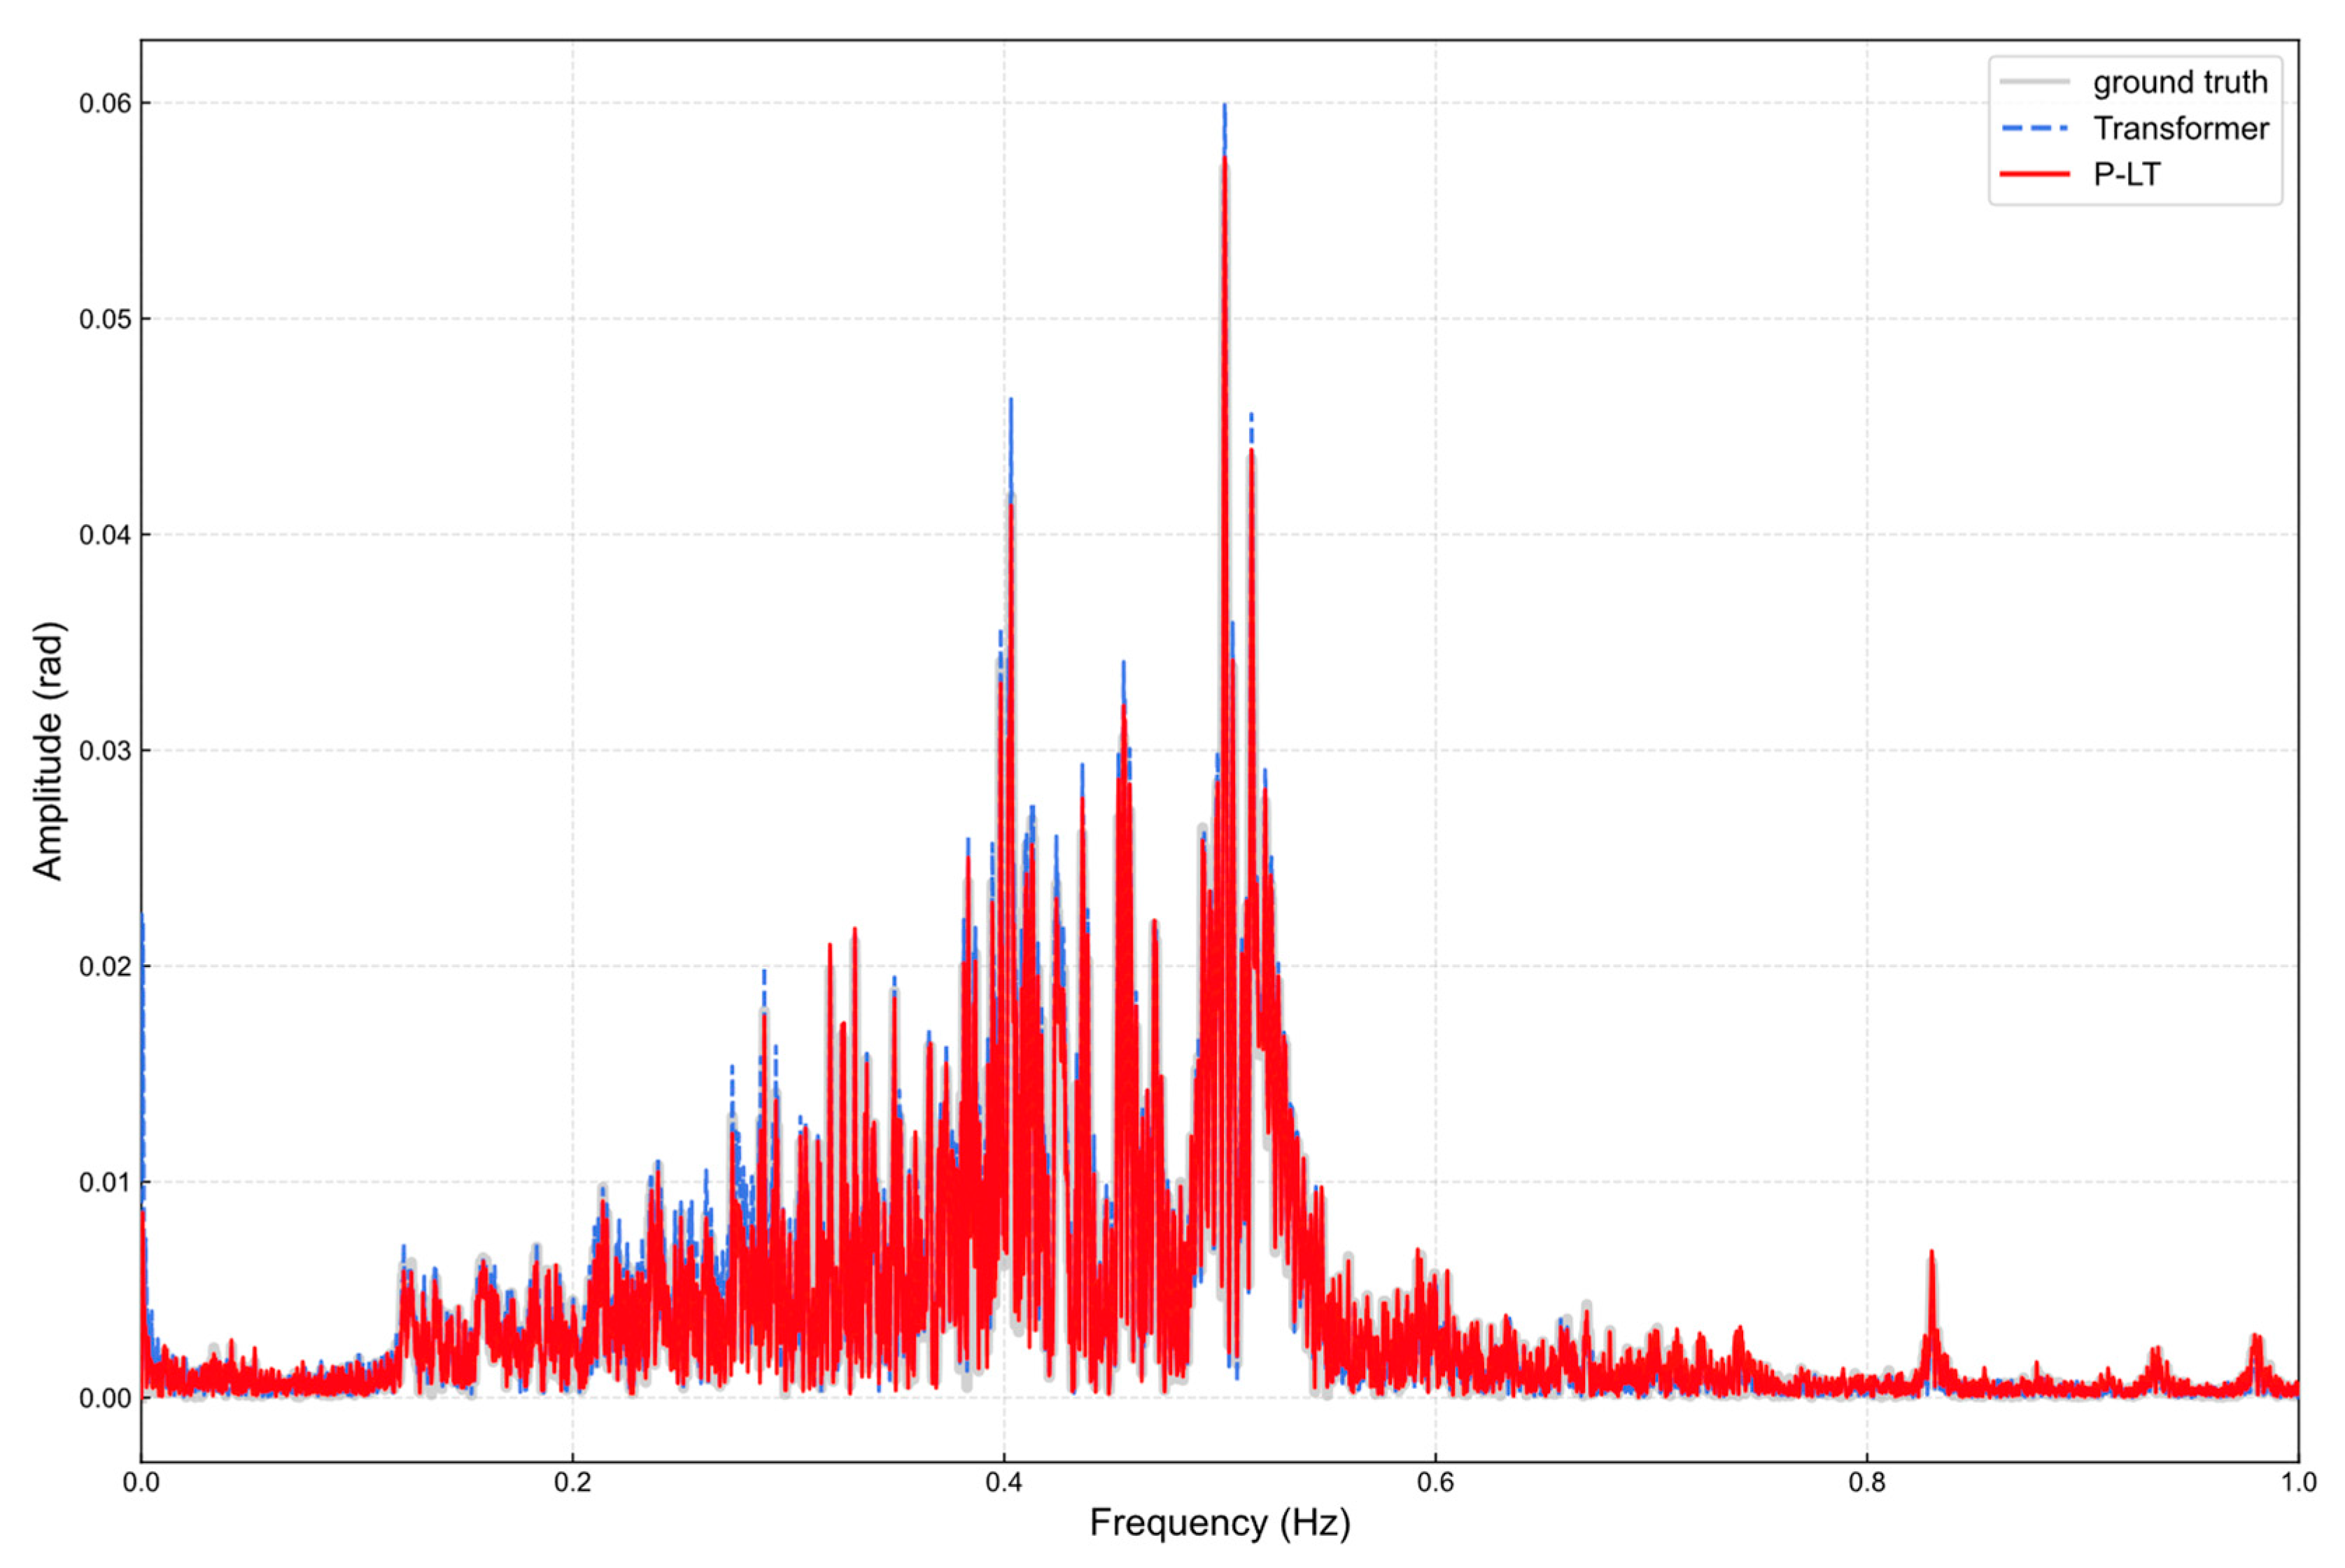
As shown in Figure 15, the roll spectrum features a distinct narrow-band resonance near the natural frequency ( Hz). The P-LT model captures this physical peak accurately, aligning closely with the simulation reference (AQWA) spectrum. The Transformer baseline diverges from the reference scope by greatly overestimating energy at Hz. This error suggests a limitation in standalone attention mechanisms: they lack an explicit inductive bias to preserve kinematic continuity and inertial structure.
Figure 15.
Comparison of roll motion frequency spectra for 90-step prediction.
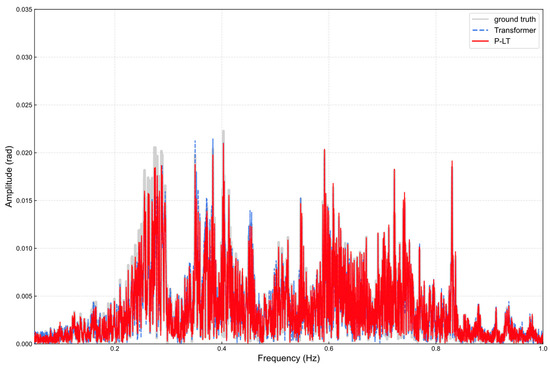
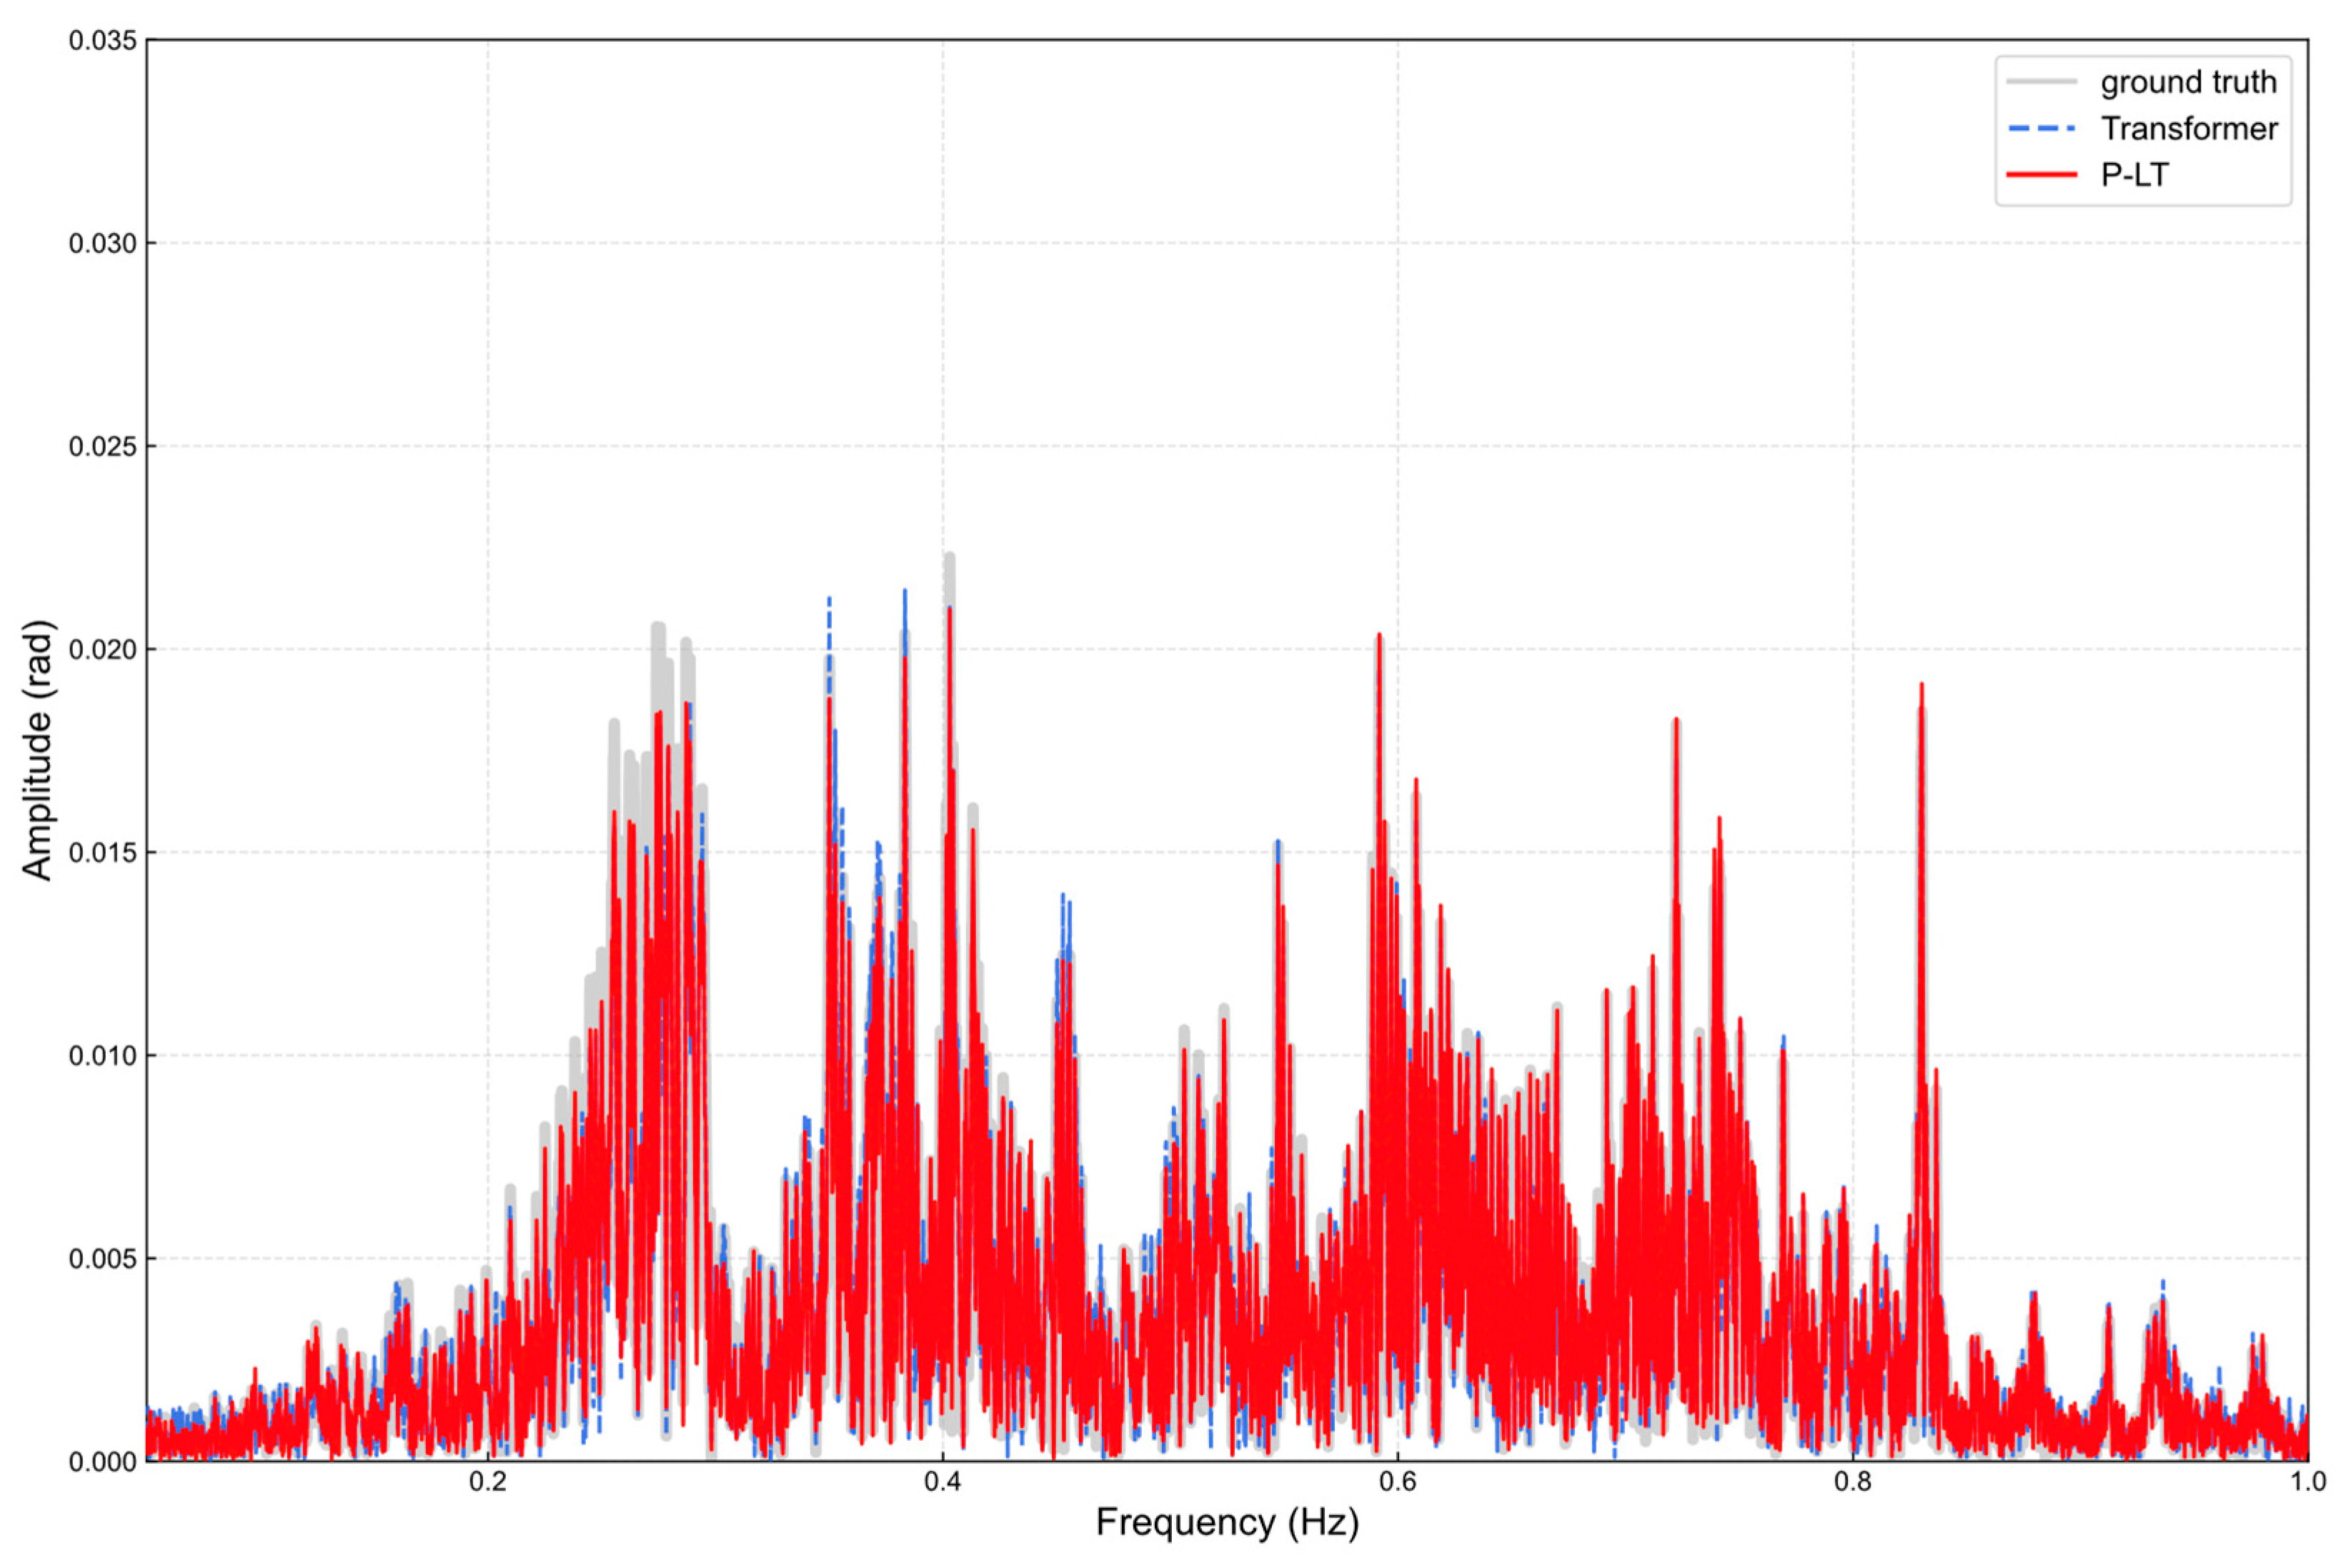
Figure 16 displays the pitch spectrum, which shows a broad-band response (0.2–0.9 Hz). The P-LT model reproduces this distribution faithfully, whereas the Transformer produces spurious energy spikes at Hz and Hz. These artifacts imply that unconstrained attention models tend to overfit accidental correlations within the short observation window. The hybrid P-LT architecture, on the other hand, relies on the LSTM to capture stepwise dependencies. This ensures that high-frequency predictions remain consistent with continuous physical motion.
Figure 16.
Comparison of pitch motion frequency spectra for the 90-step prediction.
Overall, the P-LT model’s better spectral quality stems from its hybrid design, which decouples kinematic and contextual information. Combining the temporal robustness of RNNs with the Transformer’s ability to aggregate context allows the model to suppress spectral artifacts. This approach effectively suppresses spurious high-frequency components that are often observed in pure attention-based models.
4. Discussion and Conclusions
This study introduces a hierarchical method for predicting multi-step ship motion, based on a kinematic–contextual decoupling framework that integrates physical principles. To capture the multi-scale temporal features of vessel dynamics, the proposed architecture links an LSTM encoder with a Transformer decoder. Validation relied on simulated roll, pitch, and heave data for Sea States 3 and 4, generated through ANSYS-AQWA using a JONSWAP spectrum. The evaluation benchmarked the model against representative single-structure baselines—specifically LSTM, Transformer, and TCN—within a unified testing environment. Experimental results indicate that the hybrid architecture consistently surpasses standalone models across all motion components and prediction horizons. Merging the LSTM’s strength in tracking kinematic continuity with the Transformer’s long-range modeling capabilities allows the LT model to limit error buildup over time. This approach also preserves essential motion characteristics.
Integrating particle swarm optimization allows for task-dependent hyperparameter adaptation, which improves prediction robustness. Paired bootstrap tests confirm that the hybrid models deliver statistically significant performance improvements, eliminating the possibility that these results arise from random sampling variations. While the PSO-optimized P-LT model offers slight accuracy gains, it does so at a much higher computational cost during training. The non-optimized LT model, in contrast, strikes a better balance between accuracy and efficiency. This suggests that the core performance improvement stems from the physically motivated local–global architecture, rather than from hyperparameter tuning alone.
Certain limitations define the scope of this method. On the issue of computational efficiency, the increased offline training cost is necessary to guarantee safety-critical precision, particularly for phase alignment. Runtime could be reduced in future work by narrowing the hyperparameter search space or applying early stopping strategies. Another limitation is the purely data-driven nature of the framework. Incorporating physics-based decomposition methods, such as dynamic mode decomposition (DMD) or neural operators, enhances the interpretability of the results. Concerning robustness, the kinematic-contextual decoupling theoretically accommodates kinematic shifts, such as changes in encounter frequency. The global attention mechanism functions as a soft filter, which suggests potential resilience against high-frequency sensor noise, even though this was not included in the current simulation. Finally, the dataset relies on linear potential flow theory. Although this approach is accurate for moderate conditions, it overlooks strong nonlinear effects like wave breaking. Consequently, the model’s applicability is limited in extreme sea states where viscous effects dominate.
Future work will focus on improving computational efficiency through model lightweighting and more efficient optimization strategies, as well as enhancing physical consistency and generalization by incorporating additional physical information, such as hull geometry, loading conditions, and environmental descriptors. Integrating time series modeling with non-time-dependent physical features represents a promising direction for developing more robust, interpretable, and practically applicable ship motion prediction frameworks.
Author Contributions
Conceptualization, Y.P. and L.D.; methodology, Y.P.; software, Y.P. and J.Z.; validation, Q.H., L.H. and Y.H.; formal analysis, Y.P.; investigation, J.Z.; resources, L.D. and Y.Q.; data curation, Q.H.; writing—original draft preparation, Y.P.; writing—review and editing, L.D. and Y.Q.; visualization, Y.P.; supervision, L.D.; project administration, L.D.; funding acquisition, L.D. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by the National Key Laboratory of Ship Structural Safety (NAKLAS-2025KF004-K), the National Natural Science Foundation of China (Grant number 52201368), and the National “111” Centre on Safety and Intelligent Operation of Sea Bridge (Grant number D21013).
Data Availability Statement
The data presented in this study are available upon request from the corresponding author due to some institutional restrictions.
Conflicts of Interest
The authors declare no conflicts of interest. The funders had no role in the design of the study.
References
- Schumacher, A.; Ribeiro e Silva, S.; Guedes Soares, C. Experimental and numerical study of a containership under parametric rolling conditions in waves. Ocean Eng. 2016, 124, 385–403. [Google Scholar] [CrossRef] [Scilit]
- Drzewiecki, M. The Propagation of the Waves in the CTO SA Towing Tank. Pol. Marit. Res. 2018, 25, 22–28. [Google Scholar] [CrossRef] [Scilit]
- Jiao, J.; Chen, C.; Ren, H. A comprehensive study on ship motion and load responses in short-crested irregular waves. Int. J. Nav. Archit. Ocean Eng. 2019, 11, 364–379. [Google Scholar] [CrossRef] [Scilit]
- Niklas, K.; Karczewski, A. Determination of Seakeeping Performance for a Case Study Vessel by the Strip Theory Method. Pol. Marit. Res. 2020, 27, 4–16. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Z.; Ma, N.; Shi, Q. Experimental study and uncertainty analysis on added resistance and local pressure distribution of KVLCC2 in irregular waves. Ocean Eng. 2025, 341, 122775. [Google Scholar] [CrossRef] [Scilit]
- Xue, Y.; Liu, Y.; Ji, C.; Xue, G.; Huang, S. System identification of ship dynamic model based on Gaussian process regression with input noise. Ocean Eng. 2020, 216, 107862. [Google Scholar] [CrossRef] [Scilit]
- Lee, J.H.; Nam, Y.S.; Kim, Y.; Liu, Y.; Lee, J.; Yang, H. Real-time digital twin for ship operation in waves. Ocean Eng. 2022, 266, 112867. [Google Scholar] [CrossRef] [Scilit]
- Schirmann, M.L.; Gose, J.W.; Collette, M.D. A comparison of physics-informed data-driven modeling architectures for ship motion predictions. Ocean Eng. 2023, 286, 115608. [Google Scholar] [CrossRef] [Scilit]
- Lou, J.; Wang, H.; Yuan, W.; Yi, H. Influence of sample intervals in real-sea trails on the nonparametric model of 3-DoF ship motion predictions. J. Ocean Eng. Sci. 2025, 10, 621–645. [Google Scholar] [CrossRef] [Scilit]
- Chen, C.W.; Chen, Y.; Cai, Q.W. Hydrodynamic-Interaction Analysis of an Autonomous Underwater Hovering Vehicle and Ship with Wave Effects. Symmetry 2019, 11, 1213. [Google Scholar] [CrossRef] [Scilit]
- Miao, Y.; Chen, X.; Cheng, X. Research on the dynamic responses of a multi-module offshore floating bridge based on the three-dimensional hydroelastic theory in the time domain. Ocean Eng. 2024, 313, 119314. [Google Scholar] [CrossRef] [Scilit]
- Trang, N.T.H.; Mitsuyuki, T.; Hirakawa, Y.; Sadakata, K.; Nakamura, Y. Experimental and Numerical Study on the Seakeeping Performance of a Wind-Powered Generation Ship Considering Boom Configurations. J. Mar. Sci. Eng. 2025, 13, 412. [Google Scholar] [CrossRef] [Scilit]
- Sun, H.B.; Yang, S.Q.; Xu, Y.F.; Xiao, J.F. Prediction of the Pitch and Heave Motions in Regular Waves of the DTMB 5415 Ship Using CFD and MMG. J. Mar. Sci. Eng. 2022, 10, 1358. [Google Scholar] [CrossRef] [Scilit]
- Hu, L.; Zhang, M.; Yu, X.; Yuan, Z.M.; Li, W. Real-time control of ship’s roll motion with gyrostabilisers. Ocean Eng. 2023, 285, 115348. [Google Scholar] [CrossRef] [Scilit]
- Mikkelsen, P. A machine learning algorithm to estimate hydrodynamic coefficients of a jack-up vessel in frequency domain. Ship Technol. Res. 2025, 72, 217–225. [Google Scholar] [CrossRef] [Scilit]
- Nazemian, A.; Ghadimi, P. Multi-objective optimization of trimaran sidehull arrangement via surrogate-based approach for reducing resistance and improving the seakeeping performance. Proc. Inst. Mech. Eng. Part M J. Eng. Marit. Environ. 2021, 235, 944–956. [Google Scholar] [CrossRef] [Scilit]
- Jiao, J.; Huang, S. CFD Simulation of Ship Seakeeping Performance and Slamming Loads in Bi-Directional Cross Wave. J. Mar. Sci. Eng. 2020, 8, 312. [Google Scholar] [CrossRef] [Scilit]
- Hong, X.; Zheng, G.; Cai, R.; Chen, Y.; Xiao, G. Computational Fluid Dynamics Prediction of the Sea-Keeping Behavior of High-Speed Unmanned Surface Vehicles Under the Coastal Intersecting Waves. J. Mar. Sci. Eng. 2025, 13, 83. [Google Scholar] [CrossRef] [Scilit]
- Copuroglu, H.I.; Pesman, E.; Katayama, T. Experimental and numerical investigation on the influence of bilge keel shape on roll damping. Mar. Struct. 2025, 100, 103725. [Google Scholar] [CrossRef] [Scilit]
- Kim, J.; Oh, W.; Kwon, W. A Numerical Study on the Seakeeping Performance and Ride Comfort of a Small MonoHull Vessel With and Without Hydrofoil in Regular Head Seas. J. Mar. Sci. Eng. 2025, 13, 1895. [Google Scholar] [CrossRef] [Scilit]
- Elman, J.L. Finding structure in time. Cogn. Sci. 1990, 14, 179–211. [Google Scholar] [CrossRef]
- Hochreiter, S.; Schmidhuber, J. Long Short-Term Memory. Neural Comput. 1997, 9, 1735–1780. [Google Scholar] [CrossRef] [Scilit]
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, L.; Gomez, A.N.; Kaiser, L.; Polosukhin, I. Attention Is All You Need. Adv. Neural Inf. Process. Syst. 2017, 30, 5998–6008. [Google Scholar]
- Mandal, S.; Prabaharan, N. Ocean wave forecasting using recurrent neural networks. Ocean Eng. 2006, 33, 1401–1410. [Google Scholar] [CrossRef] [Scilit]
- Abhigna, P.; Jerritta, S.; Srinivasan, R.; Rajendran, V. Analysis of feed forward and recurrent neural networks in predicting the significant wave height at the moored buoys in Bay of Bengal. In Proceedings of the 2017 International Conference on Communication and Signal Processing (ICCSP), Chennai, India, 6–8 April 2017; pp. 1856–1860. [Google Scholar]
- Sadeghifar, T.; Nouri Motlagh, M.; Torabi Azad, M.; Mohammad Mahdizadeh, M. Coastal Wave Height Prediction using Recurrent Neural Networks (RNNs) in the South Caspian Sea. Mar. Geod. 2017, 40, 454–465. [Google Scholar] [CrossRef] [Scilit]
- Osawa, K.; Hironaka, S.; Kasashima, S.; Kudo, M. Wave Height and Peak Wave Period Prediction Using Recurrent Neural Networks. In Proceedings of the 2020 International Conference on Computational Intelligence (ICCI), Bandar Seri Begawan, Brunei, 8–9 October 2020; pp. 116–121. [Google Scholar]
- Fan, S.; Xiao, N.; Dong, S. A novel model to predict significant wave height based on long short-term memory network. Ocean Eng. 2020, 205, 107298. [Google Scholar] [CrossRef] [Scilit]
- Ni, C.; Ma, X. An integrated long-short term memory algorithm for predicting polar westerlies wave height. Ocean Eng. 2020, 215, 107715. [Google Scholar] [CrossRef] [Scilit]
- Abdullah, F.A.R.; Ningsih, N.S.; Al-Khan, T.M. Significant wave height forecasting using long short-term memory neural network in Indonesian waters. J. Ocean Eng. Mar. Energy 2022, 8, 183–192. [Google Scholar] [CrossRef] [Scilit]
- Wei, Z. Forecasting wind waves in the US Atlantic Coast using an artificial neural network model: Towards an AI-based storm forecast system. Ocean Eng. 2021, 237, 109646. [Google Scholar] [CrossRef] [Scilit]
- Putri, D.A.; Adytia, D. Time Series Wave Forecasting with Transformer Model, Case Study in Pelabuhan Ratu, Indonesia. In Proceedings of the 2022 10th International Conference on Information and Communication Technology (ICoICT), Bandung, Indonesia, 2–3 August 2022; pp. 1–6. [Google Scholar]
- Shi, J.; Su, T.; Li, X.; Wang, F.; Cui, J.; Liu, Z.; Wang, J. A Machine-Learning Approach Based on Attention Mechanism for Significant Wave Height Forecasting. J. Mar. Sci. Eng. 2023, 11, 1821. [Google Scholar] [CrossRef] [Scilit]
- Yang, Y.; Peng, T.; Liao, S. Predicting 3-DoF motions of a moored barge by machine learning. J. Ocean Eng. Sci. 2023, 8, 336–343. [Google Scholar] [CrossRef] [Scilit]
- Zhang, M.; Taimuri, G.; Zhang, J.; Hirdaris, S. A deep learning method for the prediction of 6-DoF ship motions in real conditions. Proc. Inst. Mech. Eng. Part M J. Eng. Marit. Environ. 2023, 237, 887–905. [Google Scholar] [CrossRef] [Scilit]
- Liu, Y.; Lu, W.; Wang, D.; Lai, Z.; Ying, C.; Li, X.; Dong, C. Spatiotemporal wave forecast with transformer-based network: A case study for the northwestern Pacific Ocean. Ocean Model. 2024, 188, 102323. [Google Scholar] [CrossRef] [Scilit]
- Kazeminezhad, M.H.; Silva, D.; Soares, C.G. Improvement of operational wave forecasts in the Western North Atlantic Ocean with a transformer model. Ocean Eng. 2025, 342, 123085. [Google Scholar] [CrossRef] [Scilit]
- Zhang, W.; Wu, P.; Peng, Y.; Liu, D. Roll Motion Prediction of Unmanned Surface Vehicle Based on Coupled CNN and LSTM. Future Internet 2019, 11, 243. [Google Scholar] [CrossRef] [Scilit]
- Li, G.; Tang, G.; Zhang, J.; Sun, Q.; Liu, X. Short-Term Prediction of Ship Heave Motion Using a PSO-Optimized CNN-LSTM Model. J. Mar. Sci. Eng. 2025, 13, 1008. [Google Scholar] [CrossRef] [Scilit]
- Zhang, D.; Zhou, X.; Wang, Z.H.; Peng, Y.; Xie, S.R. A data driven method for multi-step prediction of ship roll motion in high sea states. Ocean Eng. 2023, 276, 114230. [Google Scholar] [CrossRef] [Scilit]
- Wang, Y.; Wang, H.; Zou, D.; Fu, H. Ship Roll Prediction Algorithm Based on Bi-LSTM-TPA Combined Model. J. Mar. Sci. Eng. 2021, 9, 387. [Google Scholar] [CrossRef] [Scilit]
- Li, S.; Wang, T.; Li, G.; Skulstad, R.; Zhang, H. Short-term ship roll motion prediction using the encoder–decoder Bi-LSTM with teacher forcing. Ocean Eng. 2024, 295, 116917. [Google Scholar] [CrossRef] [Scilit]
- Marlantes, K.E.; Maki, K.J. A hybrid data-driven model of ship roll. Ocean Eng. 2024, 303, 117821. [Google Scholar] [CrossRef] [Scilit]
- Sun, C.; Li, J.; Chen, H.; Ma, X.; Hou, Y.; Zhang, L.; Wei, Y. Prediction of ship motions in irregular waves using IPSO-optimized BP-BiLSTM parallel model. Ocean Eng. 2025, 342, 123072. [Google Scholar] [CrossRef] [Scilit]
- Yuan, P.; Zhao, W.; Zhao, Y. Intelligent prediction algorithm of ship roll and pitch motion based on SSA-optimized BiLSTM network. Ocean Eng. 2025, 320, 120331. [Google Scholar] [CrossRef] [Scilit]
- Sakovich, N.; Aksenov, D.; Pleshakova, E.; Gataullin, S. A neural operator using dynamic mode decomposition analysis to approximate partial differential equations. AIMS Math. 2025, 10, 22432–22444. [Google Scholar] [CrossRef] [Scilit]
- Nimma, R.B.; Arundeepan, V.; Shashikala, A.P. Ship motion in viscous flow under irregular waves. Int. J. Sci. Eng. Res. 2018, 9, 8–13. [Google Scholar]
- Tavakoli, S.; Singh, M.; Hosseinzadeh, S.; Hu, Z.; Shao, Y.; Wang, S.; Huang, L.; Grammatikopoulos, A.; Li, Y.P.; Khojasteh, D.; et al. A review of flexible fluid-structure interactions in the ocean: Progress, challenges, and future directions. Ocean Eng. 2025, 342, 122545. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.