


Abstract
To address the issues of imprecise user segmentation, inadequate handling of fuzzy evaluation information, and low recommendation accuracy in current electricity retail package recommendations, a novel recommendation method based on K-prototypes clustering and interval-valued intuitionistic fuzzy theory is proposed. First, a multi-dimensional user profile is constructed, incorporating five numerical tags—such as monthly average electricity consumption and monthly load factor—and two categorical tags: industry characteristics and value-added service demand. The K-prototypes algorithm is employed to cluster users, effectively resolving the profile distortion problem caused by the neglect of categorical features in traditional K-means clustering. Second, interval-valued intuitionistic fuzzy numbers are introduced to transform user linguistic evaluations into quantitative indicators. A projection measure-based model is established to objectively determine attribute weights, thereby eliminating subjective weighting bias. Finally, a comprehensive ranking of electricity retail packages is generated by integrating satisfaction levels of similar users and similar measures of new users. The recommendation performance is validated using Root Mean Square Error (RMSE), Kendall’s τ, Normalized Discounted Cumulative Gain (NDCG@5), and Discrimination Index (S). A case study involving users from a region in China demonstrates that the proposed method reduces the Root Mean Square Error (RMSE) to 0.32, which is 31.25% lower than the next best traditional method (K-prototypes + equal weight clustering with RMSE = 0.48), accurately addresses the core demands of diverse user groups, significantly improves recommendation precision and user satisfaction, and exhibits substantial practical application value.
1. Introduction
Against the backdrop of ongoing electricity market reform, the retail electricity market has become increasingly competitive. China’s power sector is progressively transitioning from “planning-oriented” to “market-oriented” mechanisms and from “uniform pricing” to “diversified competition” [1,2]. Consequently, personalized and differentiated demands for electricity consumption are becoming more prominent, with user needs shifting from “access to electricity” to “high-quality electricity usage” [3].
To more clearly position the contribution of this study, this paper explicitly focuses on a novel integration of K-prototypes clustering, interval-valued intuitionistic fuzzy evaluation, and projection-measure-based weighting, forming a unified recommendation framework for electricity retail packages. Specifically, we demonstrate that combining K-prototypes-based mixed-attribute user segmentation + IVIFN-based multi-criteria evaluation + projection-measure-driven objective weighting yields significantly improved RMSE and discrimination performance compared with existing approaches, K-means-only clustering, single-valued fuzzy evaluation, and subjective-weight-based MCDM models.
Significant differences in electricity consumption behavior, price sensitivity, and service requirements among users across industries and scales have rendered the traditional “one-size-fits-all” electricity retail package model inadequate in addressing the core demands of diverse user groups [4,5]. Large Industrial users, characterized by high-load production processes, require highly reliable power supply and equipment maintenance services; commercial users, with concentrated operating hours, prioritize peak-valley tariff optimization to reduce costs [6]; agricultural users, affected by seasonal production patterns, exhibit significant fluctuations in electricity consumption and prefer packages supporting flexible capacity mechanisms; residential users, meanwhile, focus on the energy-saving benefits of tiered electricity pricing integrated with smart home systems, seeking a balance between economy and convenience [7,8]. The notable differences among user groups in terms of load characteristics, industry attributes, and value-added service needs have raised the demand for more personalized and accurate electricity retail package recommendations.
However, traditional electricity retail package recommendation methods exhibit significant limitations when confronted with these complex demands. Firstly, in user profile construction, existing approaches predominantly rely on K-means clustering for user categorization. For instance, studies [9,10] utilize numerical indicators such as electricity consumption and load factors to build user profiles, demonstrating the usefulness of behavioral feature extraction in basic segmentation tasks. Nevertheless, these approaches treat user profiles as purely numerical vectors and systematically overlook categorical attributes such as industry characteristics, contract type, and service preferences. As a result, although the clustering structures in [9,10] are computationally efficient, they fail to capture the multidimensional heterogeneity of real users, often producing distorted or incomplete representations that reduce the downstream recommendation accuracy. Secondly, regarding user evaluation processing, certain methods adopt either single-dimensional evaluation criteria (e.g., considering only electricity pricing costs [11]) or subjective empirical weighting approaches [12]. These works provide intuitive and easy-to-implement scoring schemes and demonstrate their feasibility in simplified evaluation environments. However, methods in [11,12] typically assume fixed attribute weights and lack mechanisms for modeling the fuzziness, hesitation, and uncertainty inherently present in user evaluations. Their reliance on crisp linguistic mappings or expert-defined weights makes them insufficiently adaptive to diverse user needs, and their ranking outputs often deviate from actual user preferences—ultimately reducing user satisfaction and package adoption rates. Furthermore, prevailing recommendation models [13] generally lack effective mechanisms for integrating and quantifying multi-granularity, multi-dimensional user evaluation information [14]. These studies highlight the importance of incorporating multiple evaluation criteria, yet their aggregation frameworks tend to treat heterogeneous linguistic scales or multi-level attribute information either uniformly or through ad-hoc normalization. Consequently, existing methods [13,14] struggle to maintain semantic consistency across mixed-granularity evaluation data, and their limited ability to represent interval-valued uncertainty restricts their applicability in complex business scenarios. These limitations reinforce the need for a unified framework that can process mixed-type user attributes, model multi-granular linguistic uncertainty, and generate personalized, data-driven attribute weights while ensuring high recommendation accuracy.
Recent studies have continued to advance electricity package and tariff recommendation models by integrating clustering with fuzzy and multi-criteria decision-making techniques. Representative examples include Choquet-integral–based prospect decision models combined with customer clustering [15] and unbalanced multi-granularity fuzzy linguistic approaches with incomplete attribute weights [16]. On the methodological side, IVIF-based decision-making has also evolved rapidly, with hybrid projection-based and TOPSIS-like frameworks such as the IVIF-LogTODIM-TOPSIS model proposed by Xu et al. (2024) [17]. More recent work has further explored this research direction by focusing on electricity tariff and package recommendation under uncertainty. For instance, a study published in Electric Power Systems Research (2023) developed a fuzzy decision-making framework for tariff selection based on customer segmentation and cost-related criteria, demonstrating the effectiveness of fuzzy preference modeling while primarily relying on numerical electricity consumption features for user grouping [16]. Similarly, a recent contribution in Applied Sciences (2025) proposed an intuitionistic fuzzy multi-criteria decision-making approach to enhance robustness against linguistic uncertainty; however, it assumes predefined user groups and does not explicitly address mixed-type user heterogeneity in the clustering stage [15]. Building on these developments, this study does not aim to replace or outperform existing fuzzy or MCDM-based recommendation models in isolation. Instead, it integrates K-prototypes clustering, interval-valued intuitionistic fuzzy modeling, projection-based multi-objective weighting, and a TOPSIS-like ranking mechanism into a unified framework specifically tailored for electricity retail package evaluation. By explicitly linking mixed-type user segmentation with uncertainty-aware package-level evaluation—while avoiding the reuse of clustering-stage variables in the decision model—the proposed framework addresses methodological gaps that have not been fully considered in prior work.
In addition to K-means and K-prototypes, several clustering techniques have been developed for mixed-type data, including Gower distance combined with k-medoids and factor analysis of mixed data (FAMD) followed by K-means. These approaches are effective in handling numerical–categorical heterogeneity, particularly in small- to medium-scale datasets where flexible similarity modeling is required.
It should be noted that this study does not aim to establish a universally optimal clustering algorithm. Instead, K-prototypes is adopted due to its balance between computational efficiency, interpretability, and direct compatibility with large-scale electricity user datasets. The focus of this work is therefore on constructing a practical and scalable recommendation framework rather than optimizing clustering performance in isolation.
In response, this paper proposes an electricity retail package recommendation approach based on K-prototypes clustering and interval-valued intuitionistic fuzzy theory. The method constructs a multidimensional user profile combining numerical and categorical features, applies K-prototypes for mixed type clustering, transforms linguistic evaluations into IVIFNs to preserve uncertainty, determines objective attribute weights using projection measures, and generates full-ranking recommendations via similarity matching.
In summary, the core research claim of this study is as follows: We show that the integration of K-prototypes clustering, IVIFN-based multi-criteria decision evaluation, and projection-measure-driven attribute weighting achieves superior recommendation performance—specifically lower RMSE and higher discrimination index—compared with existing clustering-based and fuzzy-evaluation-based approaches, in the context of electricity retail package recommendation.
2. K-Prototypes-Based Partition of Sample User Sets
2.1. Establishment of a User Tagging System
Significant heterogeneity in electricity usage and consumption behavior is observed across different user groups, and these differentiated characteristics directly influence preferences for electricity retail packages. To accurately identify user demand features, a multidimensional user profiling tag system is constructed, which includes monthly average electricity consumption, monthly load factor, proportion of daily electricity consumption during peak, standard, and off-peak hours, industry characteristics, and value-added service requirements. Core indicators such as load characteristics and social attributes are quantitatively represented, enabling the systematic characterization of electricity consumption behaviors among user groups. This provides data support for identifying target groups that share similar electricity consumption characteristics with new users. Based on the specified tags—namely, monthly average electricity consumption, monthly load factor, and the proportions of daily electricity consumption during peak, standard, and off-peak hours, the tags are categorized into numerical and categorical types. The aforementioned load-related tags are classified as numerical tags [18], while industry characteristics and value-added service requirements are defined as categorical tags.
For the categorical attribute “Industry Characteristics,” the four categories (Large Industrial, Commercial, Agricultural, Residential) are treated as nominal variables and encoded using integer category labels {1,2,3,4}. This encoding does not impose any ordinal structure, as K-prototypes handles categorical mismatches through the dissimilarity function rather than numerical distance. One-hot encoding is not applied because K-prototypes requires categorical variables to be represented as discrete symbols rather than binary vectors.
The monthly load data for the user set is represented as , where denotes the -th user and represents the load data of user for a specific month. The load data is expressed as , where corresponds to the load value of user during the -th hourly period of the month, and indicates the total number of hourly periods in the month, with each period measured in hours (h). All tags are defined in accordance with Table 1.
Table 1.
Load characteristic.
In Table 1, H is defined as the total number of hours in the month, represents the electricity power at the -th hour, denotes the maximum hourly electricity power during the month, corresponds to the set of peak hours, indicates the set of standard hours, and refers to the set of off-peak hours.
The electricity consumption behavior and package selection direction of users are profoundly influenced by their industry characteristics across multiple dimensions, including consumption patterns, cost sensitivity, and policy dependency. Large Industrial users, characterized by continuous high-load production, are typically matched with high-reliability packages and demand management services, where their sensitivity to power quality directly determines the cost of additional services. Commercial users are significantly affected by time-of-use electricity pricing, with a high proportion of electricity costs during peak periods, necessitating dynamically optimized consumption strategies. Agricultural users are driven by seasonal fluctuations, experiencing a sharp increase in electricity consumption during irrigation periods, thus being suited for flexible capacity fee mechanisms and non-subsidized green electricity packages. Residential users, focused on daily living scenarios, achieve energy savings and cost reduction through tiered electricity pricing and smart home services. The demand for value-added services is classified into three tiered levels—high, medium, and low—based on the intensity of user demand, with specific categorization criteria provided in Table 2.
Table 2.
Value-added service intensity.
To clarify the distinction, “High Demand” refers to users who actively purchase two or more value-added services, whereas “Medium Demand” refers to users who utilize complimentary services provided by the electricity retailer without additional charges. Thus, the tiered categorisation explicitly differentiates between paid value-added service usage (High Demand) and no-cost or complimentary service usage (Medium Demand), avoiding any ambiguity in tag interpretation.
The user profile for user is constructed based on numerical and categorical tags, represented as , which reflects the energy consumption habits of user and provides the foundation for identifying groups with similar energy consumption behaviors as well as enabling accurate electricity retail package recommendations for new users. The numerical tags , , , , correspond to the monthly average electricity consumption, monthly load rate, proportion of daily electricity consumption during peak hours, proportion during standard hours, and proportion during off-peak hours of user , respectively, while the categorical tags , represent the industry characteristics and value-added service demand of user , respectively. It should be noted that the categorical tag “value-added service demand” used at this stage reflects users’ long-term service preference tendencies (e.g., reliance on basic electricity supply versus active demand for supplementary services). This tag is introduced solely to enhance user segmentation in the clustering process and does not participate in the subsequent evaluation or ranking of electricity retail packages.
2.2. Sample User Partitioning Method Based on K-Prototypes
Given the substantial number of users, clustering must be performed on users with similar profiles to reduce computational load. In traditional electricity retail package recommendations, user grouping has been solely based on K-means clustering of numerical features. In contrast, the K-prototypes clustering algorithm effectively addresses the long-overlooked issue of incorporating categorical tags—such as industry characteristics and service preferences—into the clustering process, thereby avoiding the distortion of user profiles caused by single-dimensional analysis. Since sample user profiles contain both numerical features (e.g., monthly average electricity consumption and monthly load factor) and categorical tags (e.g., industry characteristics and value-added service demand), the K-prototypes algorithm is adopted in this study to cluster users with mixed-attribute data [19]. This algorithm innovatively integrates the Euclidean distance measurement used in K-means for numerical variables and the Hamming distance measurement employed in K-modes for categorical variables. By constructing a dissimilarity function, simultaneous processing of numerical and categorical attributes is achieved. The specific steps are as follows:
The clustering process is initialized with k Clusters, where each sample is composed of both numerical and categorical attributes. The numerical attributes are represented as , where , , , , correspond to the monthly average electricity consumption, monthly load factor, daily peak electricity consumption proportion, daily standard electricity consumption proportion, and daily off-peak electricity consumption proportion of user , respectively. The categorical attributes are denoted as , representing the industry characteristics and service preferences of user .
k prototype sample users are selected as initial cluster centers using the standard Huang initialization strategy for K-prototypes. This strategy first randomly selects one object and subsequently iteratively selects the remaining centers by maximizing the mixed dissimilarity with respect to the already selected center, denoted by , where represents the cluster centers after 0 iterations. In addition, a purely random initialization that selects k samples uniformly at random is used only for robustness analysis, rather than as the default initialization strategy.
For each sample user , the mixed dissimilarity to all cluster centers is calculated using the following formula:
where is defined as , denotes the numerical dissimilarity measure, refers to the categorical dissimilarity measure, and the weighting between these two components in the mixed dissimilarity measure is controlled by the parameter . In this study, is fixed to 1.0 for all experiments to ensure a balanced contribution of numerical and categorical attributes.
Each sample user is then assigned to the nearest cluster according to the following criterion:
To address potential deviations of initial cluster centers from the true distribution, which may lead to incorrect grouping that cannot be subsequently corrected, the cluster centers are updated such that each center becomes the geometric centroid of all samples within its respective cluster.
In Equation (5), the numerical tags of the cluster center are updated using the mean value, while Equation (6) utilizes the mode value for updating the categorical tags, where represents the indicator function employed for counting category frequencies.
The aforementioned procedure is repeated iteratively until the following condition is satisfied:
In this formulation, is defined as the cluster center obtained after the -th iteration, and in the numerical implementation the algorithm is terminated when the -norm of the change in all cluster centers between two successive iterations satisfies or when the number of iterations reaches 100, whichever occurs first. In all experiments the former condition was met within 30 iterations.
In summary, the procedure for partitioning the sample user set based on K-prototypes clustering is implemented through the following steps:
Step 1: The value of k is initialized, and the initial set of cluster centers is generated using the Huang initialization strategy, which first randomly selects one sample and then iteratively selects the remaining centers by maximizing the mixed dissimilarity.
Step 2: For each user , the mixed dissimilarity to each cluster center is calculated, and the user is assigned to the cluster with the minimum dissimilarity.
Step 3: After all users are assigned, the cluster centers are updated according to the center update algorithm.
Step 4: Steps 2 and 3 are repeated iteratively until the cluster centers remain unchanged and the mixed dissimilarity is minimized, which in practice corresponds to the -norm of the change in all cluster centers falling below or the number of iterations reaching 100; in all experiments, convergence was achieved well before this upper iteration limit.
3. Interval-Valued Intuitionistic Fuzzy-Based Evaluation Matrix Construction for Electricity Retail Packages
The set of electricity retail packages is defined as , and the user set is characterized by an attribute set , which represents the criteria for evaluating the electricity retail packages. Here, denotes the j-th electricity retail package, refers to the k-th evaluation attribute of the electricity retail packages assessed by the user set , J indicates the total number of electricity retail packages, and K represents the total number of evaluation attributes. The attributes considered in this study for the electricity retail packages include base electricity price, renewable energy proportion, value-added services, and contract flexibility.
During the electricity retail package recommendation process, user evaluations of package attributes are often characterized by fuzziness and uncertainty. To accurately capture subjective user evaluation information, interval-valued intuitionistic fuzzy numbers (IVIFNs) are introduced in this study to construct an evaluation matrix. This matrix simultaneously represents the degrees of satisfaction, dissatisfaction, and hesitation in user evaluations, while preserving the fuzzy characteristics of the assessments through interval-based representations.
Interval-valued intuitionistic fuzzy sets have been widely adopted in multi-criteria decision-making problems to handle uncertainty, hesitation, and incomplete preference information. Representative IVIF-based MCDM approaches include IVIF-TOPSIS and IVIF-VIKOR, which emphasize closeness to ideal solutions or compromise ranking strategies under objective or subjective weighting schemes. To clarify the positioning of the proposed decision model, a brief comparison with representative IVIF-based MCDM methods is provided below.
As summarized in Table 3, existing IVIF-based MCDM methods are effective for general ranking problems, whereas the proposed approach focuses on enhancing discrimination among closely ranked alternatives. Based on this motivation, the following subsections detail the construction of the IVIF evaluation matrix and the subsequent projection-measure-based decision model.
Table 3.
Comparison of representative IVIF-based MCDM approaches.
The user is assumed to evaluate package attributes using a -level rating scale, where the linguistic term set for is defined as , in which is an odd number representing the granularity of the linguistic term set and denotes the -th linguistic term in the set with granularity , where p = 0 corresponds to the most negative evaluation and p = t − 1 corresponds to the most positive evaluation. For example, a 7-granularity linguistic term set is defined as .
3.1. Mapping of User Package Linguistic Evaluations to Interval-Valued Intuitionistic Fuzzy Numbers
To accurately quantify the fuzziness and uncertainty inherent in user evaluations, discrete linguistic terms are required to be transformed into mathematical expressions in continuous interval form. Interval-Valued Intuitionistic Fuzzy Numbers (IVIFNs) systematically characterize user evaluations through three dimensions: membership degree intervals, non-membership degree intervals, and hesitancy degree intervals, thereby capturing the degrees of satisfaction, dissatisfaction, and uncertainty ranges in user assessments and overcoming the limitations of traditional fuzzy sets with single membership functions. This mapping method preserves the semantic features of linguistic terms while integrating cognitive differences among users through interval operations. The specific procedure is described as follows:
First, the membership degree interval is calculated using the following formula:
where and are defined as the lower and upper bounds of the user’s satisfaction degree with the attribute, respectively, t denotes the granularity of the linguistic term set, p represents the subscript of the linguistic term in the evaluation set, and is the interval radius used to control the range of fuzziness.
The non-membership degree interval is subsequently calculated using the following formula:
where and are defined as the lower and upper bounds of the user’s dissatisfaction degree with the attribute, respectively. controls the level of fuzziness when transforming linguistic terms into Interval-Valued Intuitionistic Fuzzy Numbers (IVIFNs). A larger value results in wider membership and non-membership intervals, indicating a higher tolerance for uncertainty in user evaluations.
Basis for Value Selection: To ensure that the converted IVIFNs satisfy the fundamental axiom μu + νu ≤ 1, while preserving the semantic distinction between linguistic terms, we refer to common practices in the literature for handling fuzzy linguistic conversions. In this paper, we set . This value ensures that for a 7-granularity linguistic term set, the IVIFN intervals converted from adjacent terms (e.g., “good” and “very good”) have a moderate degree of overlap. This reflects the fuzziness of evaluations while avoiding excessive confusion between different grades, aligning with the cognitive characteristics of decision-makers in fuzzy environments.
Finally, the IVIFN is generated as , which is required to satisfy the condition . If this condition is not met, the parameter is adjusted accordingly.
3.2. Construction of an Interval-Valued Intuitionistic Fuzzy Evaluation Matrix for Electricity Retail Packages
Due to variations in knowledge, cultural background, and information sources among users, different granularities of linguistic term sets are adopted by different users. To ensure comparability of user evaluation information and fairness in decision-making, linguistic evaluations from diverse users are unified to a benchmark granularity scale. This process eliminates cognitive biases caused by differences in evaluation scales and achieves standardized equivalent processing of user evaluation information [20]. The corresponding formula is provided as follows:
Although rounding may lead to minor information loss, it was selected because the decision-making context requires discrete linguistic labels, and preliminary tests showed that more sophisticated fuzzy transformation operators did not change the ranking results. The rounding-based unification therefore ensures interpretability, transparency, and reproducibility without affecting decision consistency. Where is defined as the corresponding index in the benchmark granularity evaluation set, represents the granularity of the linguistic term set actually employed by the user, and denotes the target granularity of the linguistic term set for unified conversion.
The equivalent electricity retail package evaluation matrix is denoted as , where represents the evaluation information of user for attribute of electricity retail package under the unified granularity, expressed as:
4. Determination of Electricity Retail Package Attribute Weights and Ranking Based on Projection Measure and Interval-Valued Intuitionistic Fuzzy Numbers
For convenience in the decision-making process, the following index sets are introduced: Let the user set be denoted as the attribute dimension set for electricity retail packages as the set of alternative packages for the decision problem as , the set of evaluation attributes for the decision problem as , and the weight vector for the evaluation attributes as , where and .
Assume a user evaluates attribute , with the evaluation attribute value being an interval-valued intuitionistic fuzzy number (IVIFN): , where , represents the user’s degree of satisfaction with attribute of package , represents the user’s degree of dissatisfaction with attribute of package , satisfying , , . The collected evaluation matrix is denoted as . Considering situations where the evaluation attribute weights are completely unknown, it is still necessary to determine the weights for each attribute. Based on the projection measure and interval-valued intuitionistic fuzzy processing method, the specific implementation steps of the proposed decision model are as follows:
First, to facilitate comprehensive information processing, the user’s decision evaluation matrix for electricity retail packages is established based on the user’s interval-valued intuitionistic fuzzy numbers, according to Ref. [21].
where: c, i represents the user’s decision evaluation information for alternative .
: The decision evaluation matrix for electricity retail packages, constructed based on user evaluations.
: The decision evaluation information for alternative , i.e., the -th row of matrix .
: The Interval-Valued Intuitionistic Fuzzy Number (IVIFN) representing user ’s evaluation of attribute of an electricity retail package.
: Total number of users (or alternatives under consideration).
: Total number of evaluation attributes.
Since different users attach different levels of importance to each attribute of the electricity retail packages, the decision evaluation matrix needs to be weighted. Based on the user’s decision evaluation matrix for electricity retail packages and the decision problem’s evaluation attribute set , the weighted decision evaluation matrix is established:
where, represents the user’s weighted evaluation matrix for alternative , . And , , , , .
To better determine the user’s degree of satisfaction and suitability for the electricity retail packages, the concepts of positive and negative ideal solutions are introduced here. The positive ideal solution represents the user’s degree of satisfaction with a certain attribute of the package; a larger value indicates greater satisfaction. The negative ideal solution represents the user’s degree of dissatisfaction with a certain attribute of the package; a larger value indicates greater dissatisfaction. Based on the weighted user decision evaluation matrix, the positive and negative ideal solutions are determined as:
where ,
To obtain more accurate results, considering that different users have different levels of importance for different attributes of the same electricity retail package, and based on the weighting concept of the decision evaluation matrix, the weighted positive and negative ideal solutions are obtained as:
where , .
The similarity between the interval-valued intuitionistic fuzzy number vectors of existing users and the target user’s fuzzy number vectors can be utilized to better complete the recommendation of electricity retail packages. Based on the interval-valued intuitionistic fuzzy projection measure, the closeness degree between two interval-valued intuitionistic fuzzy number vectors, i.e., the similarity between the decision evaluation sets of the target user and existing users, is determined according to Ref. [22]. Using the clustering method from Section 2.2 to measure the closeness between two IVIFN vectors, the standardized projection values of each alternative’s attribute evaluation values with the weighted positive and negative ideal solutions are calculated respectively:
where:
: Standardized projection of alternative ’s weighted evaluation vector onto the weighted .
: Standardized projection of alternative ’s weighted evaluation vector onto the weighted .
Determining the target user’s level of importance for a specific attribute of an electricity retail package, i.e., determining the weight of that attribute, aims to achieve better discrimination in the projection values between each alternative and the positive ideal solution, and simultaneously better discrimination in the projection values between each alternative and the negative ideal solution. Based on this idea, an objective weighting method for determining attribute weights is derived, which maximizes the difference between the maximum and minimum projection values of all alternatives with the positive ideal solution, and also maximizes the difference between the maximum and minimum projection values of all alternatives with the negative ideal solution. Introducing the standardized projection measure method and considering situations with incomplete weight information, the following multi-objective programming model, denoted as Model I, is established:
where:
: Objective function maximizing the discrimination (range) of projection values to the PIS.
: Objective function maximizing the discrimination (range) of projection values to the NIS.
: Vector of attribute weights to be determined.
Let the standardized projection measures be: and
where:
is the weight of the -th attribute
is the projection distance between interval intuitionistic fuzzy numbers;
is the evaluation value of package on attribute ;
and are the values of the positive and negative ideal solutions on attribute , respectively.
Objective function:
Constraints:
Introducing a preference coefficient , Model I can be transformed into the following single-objective programming model, denoted as Model II:
where:
: Combined single objective function.
: Preference coefficient (), balancing the importance
: Focus only on (17).
: Focus only on (18).
: Equal importance.
The selection of the preference coefficient λ depends on the decision-maker’s consideration of the discrimination between alternatives and the positive/negative ideal solutions. By setting the preference coefficient λ and solving the above optimization Model II, the attribute weight vector can be obtained.
λ balances the decision-maker’s relative preference between discriminating “closeness to the positive ideal solution” and “distance from the negative ideal solution”. λ → 1 indicates complete reliance on the positive ideal solution (pursuing the optimal); λ → 0 indicates complete reliance on the negative ideal solution (avoiding the worst); λ = 0.5 indicates equal importance.
Baseline Value: In the absence of prior preference information, to reflect a balanced consideration of “pursuing satisfaction” and “avoiding dissatisfaction,” we set λ = 0.5 in the main experiments of this paper. This is a common and neutral baseline setting, suitable for most decision scenarios without a clear inclination.
The core idea behind the objective weight determination model constructed in this paper stems from an intuitive decision principle: an effective decision model should be able to clearly distinguish between different alternatives. Within the projection measure-based framework, the standardized projection value between alternative and the positive ideal solution quantifies its “degree of approaching the optimal,” while the standardized projection value between and the negative ideal solution quantifies its “degree of avoiding the inferior.”
If the values calculated for all alternatives under a given weight vector are very close (i.e., is small), it means that under this weight configuration, all alternatives are difficult to distinguish in the dimension of “approaching the optimal,” and the model loses its ability to identify the best solution. Similarly, if the values are very close (i.e., is small), the model lacks discriminative power in the dimension of “avoiding the inferior,” failing to effectively identify the disadvantaged solutions that should be avoided.
Therefore, to obtain attribute weights with high discriminative power, we naturally seek a weight vector w such that:
The distribution of all alternatives in the “approaching the optimal” dimension is as dispersed as possible, i.e., maximizing = .
The distribution of all alternatives in the “avoiding the inferior” dimension is also as dispersed as possible, i.e., maximizing = .
This is equivalent to finding a scaling method for the coordinate axes (attribute weights) in the “alternative-dimension” space constituted by the projection values, so that the projected coordinates of the alternative points in the directions of the positive and negative ideal solutions have the maximum range. Maximizing ensures that the gap between the best and worst alternatives in terms of “satisfaction” is widened; maximizing ensures that the gap between the most-to-be-avoided and the least-to-be-avoided alternatives in terms of “dissatisfaction” is widened. By simultaneously optimizing these two objectives (Model I), the resulting weight vector w maximizes the overall resolution capability of the decision model, thereby providing a foundation with the highest discrimination for the subsequent ranking based on the idea (Equation (21)).
After solving the single-objective programming model and calculating the weight vector, to obtain the similarity degree between each alternative and the optimal solution, a based on the standardized projection measure can be defined, following the idea of the method:
where:
: Normalized Relative Closeness coefficient for alternative .
: Projection to weighted PIS (Equation (17)).
: Projection to weighted NIS (Equation (18)).
Following step five to solve for the attribute weight vector, substitute it back into Equations (17) and (18) to respectively obtain the standardized projection values of each alternative package’s attribute evaluation values with the positive and negative ideal solutions. Then, calculate the correlation coefficient for each alternative package using Equation (21).
Finally, rank the electricity retail packages for recommendation based on the calculated correlation coefficient for each alternative . The ranking criterion is: the larger the correlation coefficient , the better the corresponding alternative , and the higher its ranking.
In summary, the steps for determining attribute weights based on projection measure and interval-valued intuitionistic fuzzy numbers, and ranking electricity retail packages, are as follows.
Step 1: Establish the decision evaluation matrix based on user evaluations.
Step 2: Establish the weighted decision evaluation matrix based on the evaluation attribute set .
Step 3: Determine the positive and negative ideal solutions and their weighted results based on the user’s satisfaction degree with attribute of package .
Step 4: Calculate the standardized projection values of each alternative’s attribute evaluation values with the weighted positive and negative ideal solutions using the standardized projection formula.
Step 5: Determine the attribute weights using the single-objective programming model, obtaining the attribute weight vector .
Step 6: Calculate the correlation coefficient based on the TOPSIS method idea.
Step 7: Rank the electricity retail packages for recommendation based on the correlation coefficient .
5. Full Ranking Recommendation of Electricity Retail Packages Based on User Satisfaction
The preceding sections constructed a comprehensive evaluation model for electricity retail packages based on projection measure and interval-valued intuitionistic fuzzy theory, using existing users’ evaluation information, resulting in the correlation coefficients (or the original interval-valued intuitionistic fuzzy evaluation matrices). These results provide a quantitative representation of historical users’ preferences for packages. Building upon this foundation, this section addresses the challenge that new users cannot directly apply the aforementioned model due to lack of historical evaluation data, and proposes a personalized full-ranking recommendation method based on similar user matching and satisfaction fusion.
Let the set of new users be , where is the -th new user, and is the total number of new users. Based on the profile of each new user :
Calculate the distance between each cluster center under the optimal cluster number and . The cluster corresponding to the smallest distance identifies users considered similar to new user , denoted as:
where, is the total number of users similar to new user , and -th user similar to new user under the optimal cluster number . The similarity matrix between new user and the similar users is represented as . It should be noted that the monthly load data for new users is unknown and must be predicted using load forecasting methods.
The monthly load data for the new user is unknown, but it can be predicted by combining the historical load data of similar users from its cluster group with time series decomposition methods. The prediction model consists of the following three steps:
Step 1: Extract historical load sequences of similar users
Let the cluster to which the new user belongs be , and the set of similar users be . The historical monthly load sequence for each similar user is:
where is the number of time intervals in a month (e.g., 24 h × 30 days).
Step 2: Construct a typical load profile (TLP)
By averaging the historical loads of similar users over each time interval, the typical daily load curve for cluster is obtained: where is the number of days of historical data.
Step 3: Monthly load prediction based on STL decomposition
The Seasonal-Trend decomposition using Loess (STL) method is applied to the typical load curve to extract its trend, seasonal, and residual components: .
Trend component : Reflects long-term load variations and can be fitted using linear or polynomial functions.
Seasonal component : Captures daily or weekly periodic patterns.
Residual component : Represents random fluctuations.
The predicted monthly load for the new user is: , where is a random perturbation term generated based on the historical residual distribution.
Based on the equivalent evaluation information of similar users for electricity retail packages, the expectation of the users’ evaluation information is calculated to obtain the similar users’ satisfaction matrix for electricity retail packages , where represents user ’s satisfaction with electricity retail package , i.e.,:
The new user’s satisfaction with an electricity retail package depends on the similar users’ package satisfaction and the similarity between the new user and the similar users. Thus, the satisfaction of new user with electricity retail package is:
where, is the satisfaction of the for new user with electricity retail package .
Based on the quantified results of new user satisfaction, this paper proposes a full ranking recommendation method for electricity retail packages. That is, the electricity retail company will rank all electricity retail packages based on the new user’s satisfaction and recommend all packages along with their corresponding ranking results to the new user for purchase selection.
To measure the effectiveness of the proposed full ranking recommendation method, the Root Mean Square Error (RMSE) is calculated based on the ranking results. The deviation of the electricity retail package recommendation result for new user can be expressed as:
where: and are the actual ranking result and the algorithm-derived ranking result, respectively, for package recommended to . The smaller the RMSE for electricity retail package recommendation, the better the recommendation effect of the proposed algorithm.
To further verify the rationality and feasibility of the proposed electricity retail package recommendation method, this paper compares it with the following three recommendation methods. To more intuitively illustrate the superiority of the proposed model, the discrimination metric formula is used to evaluate the model.
For the model, represents that there are a total of alternative schemes, represents the comprehensive evaluation score value of the -th alternative scheme, represents the average value of the comprehensive evaluation scores, and is calculated according to different conditions. It can be seen that: the larger the discrimination , the better the discrimination of the decision model.
In summary, the electricity retail package recommendation method proposed in this paper, based on the sample user evaluation information database, provides electricity retail package recommendations for new users. The flowchart of the electricity retail package recommendation based on K-prototypes clustering and interval-valued intuitionistic fuzzy theory is shown in Figure 1.
Figure 1.
Flowchart of Electricity Billing Package Recommendation based on K-prototypes Clustering and Interval Intuitionistic Fuzzy Theory.
6. Case Analysis
In the experimental evaluation, the mixed dissimilarity trade-off parameter in the K-prototypes clustering algorithm is set to 1.0 as the baseline value. All reported results in Section 6.1 and Section 6.2 are obtained under this setting, unless otherwise stated.
To validate the effectiveness and practicality of the “K-Prototypes Clustering Interval Intuitionistic Fuzzy Decision-Making” electricity package recommendation method proposed in this paper, this case study analyzes real business data from a regional electricity retailer through two dimensions: “Recommendation Result Presentation” and “Method Performance Comparison”. The experimental data includes 10,000 user electricity consumption records (covering four categories: Large Industrial, Commercial, Agricultural, and Residential users) and information on 20 available packages. Spanning a 12-month period, the dataset comprehensively contains user load characteristics (monthly average electricity consumption, peak-valley load ratio), industry attributes, value-added service demands, and other labels, fully simulating authentic electricity retail business scenarios.
Due to contractual confidentiality constraints with the electricity retailer, the real consumption dataset cannot be released publicly. To preserve reproducibility, we provide a complete data schema, full hyperparameter specifications, and detailed algorithmic workflows that enable independent reconstruction of compatible datasets. Synthetic datasets and demonstration scripts can be supplied upon reasonable request to the corresponding author.
This case study first presents the core electricity sales package recommendation results in Section 6.1, including user clustering outcomes based on K-prototypes (intuitively visualized through curves to demonstrate cluster stability and user segmentation characteristics) and package recommendations tailored for different clustered groups (concretely presented in tables to clarify optimal package matching relationships). Subsequently, Section 6.2 validates the superiority of our approach over traditional methods through comparative experiments, evaluating both clustering algorithm performance and recommendation method accuracy. Finally, Section 6.3 summarizes key conclusions from this case study, providing data-driven support for electricity retailers’ customer segmentation and package recommendation operations.
6.1. Recommended Results for Electricity Packages
The effectiveness of electricity package recommendation results depends on two key components: “precise user clustering” and “tailored package matching”. This section first clusters 10,000 user data points using the K-prototypes algorithm, then recommends suitable electricity packages based on each group’s consumption patterns and evaluation preferences. The specific results are as follows.
User Clustering Results
Based on the 7-dimensional user labels constructed in the previous section (5 numerical indicators: monthly average electricity consumption, monthly load rate, daily peak/normal/off-peak electricity consumption ratio; 2 categorical types: industry characteristics and value-added service demands), we conducted clustering using the K-prototypes algorithm. The corresponding elbow plot is shown in Figure 2. Through elbow method analysis, the optimal number of clusters was determined to be 4, which broadly corresponds to the four major user categories commonly used in actual business operations (Large Industrial, Commercial, Agricultural, and Residential), rather than being imposed as a hard constraint a priori. In addition to the elbow method, we also conducted a quantitative silhouette-based validation over , and k = 4 achieved the highest average silhouette score (0.42), providing a quantitative justification for selecting this value. To visually demonstrate the clustering results, we plotted the cluster distribution curve using “time-period power load” as a two-dimensional feature, with the results shown in Figure 3.
Figure 2.
Elbow plot for selecting k ∈ {3, 4, 5, 6} (x-axis: number of clusters k; y-axis: WCSS).
Figure 3.
Distribution Curves of Four User Groups.
The first two principal components were selected as the core visualization dimensions for three key reasons: Firstly, their combined variance contribution reaches 89.7% (62.3% for the first component and 27.4% for the second), preserving critical information from the original 7-dimensional dataset with minimal loss. Secondly, these components carry clear physical meanings—corresponding to “scale and stability of electricity consumption” and “time distribution of electricity usage and service demand”—which precisely align with the core logic of user segmentation and the decision-making basis for electricity package recommendations. Thirdly, the clustering results in this two-dimensional space exhibit high consistency with the original high-dimensional data (adjusted Rand Index ARI = 0.92), faithfully representing the true distribution of user groups and ensuring reliable and intuitive visualization.
In Figure 2, the horizontal axis is the daily timetable, the vertical axis is the power load size, and the curve shows the characteristic distribution density of each cluster group.
The chart clearly shows distinct boundaries between the electricity load characteristics of four user groups, with no significant overlap. Industrial users exhibit high peak loads that last longer, commercial users maintain stable daytime peaks, agricultural users show generally low and minimal fluctuations, while residential users experience noticeable morning and evening surges. These patterns align with real-world usage scenarios, demonstrating the chart’s effectiveness in highlighting differences across user categories. This provides a solid analytical foundation for future power resource allocation and related tasks.
At the recommendation stage, value-added services are considered as package-level configuration attributes (e.g., maintenance services, data analysis services, and smart energy management services), which are evaluated independently through users’ linguistic assessments in the interval-valued intuitionistic fuzzy decision model. Based on the electricity consumption characteristics and the overall service preference profiles of each cluster group, and combined with the “package satisfaction score” calculated by interval intuitionistic fuzzy decision model (full score of 10 points, the higher the score, the stronger the adaptability), the optimal package is recommended for each of the four user groups, as shown in Table 3.
Although the terms “value-added service demand” and “value-added services” are semantically related, they are introduced at different modeling stages and serve distinct purposes: the former affects user grouping, while the latter is evaluated at the package level for ranking. No categorical tag or intermediate result from the clustering stage is reused or propagated into the interval-valued intuitionistic fuzzy evaluation process, thereby avoiding feature reuse or conceptual double counting.
The recommendation results demonstrate that the packages are highly aligned with user group needs: equipment maintenance for large industrial users, peak-valley optimization for commercial users, flexible capacity solutions for agricultural users, and tiered energy-saving plans for residential users all precisely address core pain points. With satisfaction scores consistently exceeding 8.5, these findings validate the recommendation model’s effectiveness in translating user characteristics into tailored package selections, proving its practical value in real-world business applications.
6.2. Comparative Analysis of Different Methodologies
To demonstrate the superiority of our proposed method, this section compares it with traditional approaches from two dimensions: “cluster algorithm performance” and “recommendation method accuracy”. Section 6.2.1 evaluates the clustering effectiveness between K-prototypes (our algorithm) and K-means (traditional method), while Section 6.2.2 compares the recommendation accuracy of our method with three conventional recommendation methods. The evaluation metrics reference the cluster quality (Rand Index, RI, and Normalized Mutual Information, NMI, computed without using the “industry characteristics” tag as a clustering feature), efficiency (convergence time), recommendation precision (Root Mean Square Error, RMSE), and discrimination (S) mentioned in Reference [23]. To verify that the observed performance differences were not caused by random fluctuations, paired two-sample t-tests were conducted for all comparative results in Table 4, Table 5 and Table 6, particularly for the RMSE and discrimination index reported in Table 6. The statistical testing procedure follows standard assumptions of paired measurement comparison.
6.2.1. Analysis of the Influence of Different Clustering Algorithms on Clustering Effect
The K-means algorithm (handling only numerical features) and the K-prototypes algorithm (handling mixed attribute features) proposed in this paper were compared from three dimensions: clustering quality, stability of cluster count, and computational efficiency. The experimental datasets included sizes of N = 100, 500, 1000, 5000, and 10,000 (covering small to large-scale data scenarios). The results are as follows.
Cluster Quality Comparison
The Rand Index (RI, measuring the consistency between clusters and true labels, with values ranging from 0 to 1, where closer to 1 is better) and normalized mutual information (NMI, measuring the similarity between cluster structure and true classification, with values ranging from 0 to 1, where closer to 1 is better) were used as evaluation indicators. To avoid tautological inflation of these metrics caused by overlapping information between clustering features and external labels, the “industry characteristics” tag in the user profile was removed from the clustering feature space in this experiment; clusters were obtained using the five load-related numerical tags together with the value-added service demand level, while the four user categories (Large Industrial, Commercial, Agricultural, Residential) recorded in the business system served as external reference labels that are not directly fed into the distance function.
For each algorithm and dataset size, we performed 10 independent runs with different random seeds; each run used the Huang initialization strategy for the initial centers and the stopping rule described in Section 2.2. The mean values and standard deviations across these 10 runs were computed, and the mean results are reported in Table 4. Across all settings, the standard deviations of RI and NMI were below 0.01, indicating that the clustering performance remains highly stable under different parameter configurations. In addition, a sensitivity analysis using purely random initialization (not tabulated for brevity) produced RI/NMI differences within this standard-deviation range and did not change the ranking between K-means and K-prototypes, confirming that the conclusions are robust with respect to the choice of initial centers.
Table 4.
Recommended Electricity Sales Packages for Four User Groups.
The mean values of 10 repeated experiments were calculated, and the results are shown in Table 5.
Table 5.
Comparison of Clustering Quality Between Two Clustering Algorithms.
The results demonstrate that as the dataset size increases, K-means’ RI and NMI values continue to decline, dropping to merely 0.50 and 0.46 at N = 10,000. In contrast, K-prototypes maintains stable values above 0.70 throughout, with the performance gap becoming more pronounced as the data scale expands. This disparity stems from K-means’ inability to exploit categorical structure in user profiles (such as differences in value-added service demand levels and other non-load attributes), which is crucial for distinguishing users with similar peak-period shares but different business requirements, leading to clustering bias. Conversely, K-prototypes effectively combines Euclidean distance (for numerical features) with Hamming distance (for categorical features), enabling it to maintain a cluster structure that is more consistent with the external user-category labels even when the “industry characteristics” tag is excluded from the feature space in the RI/NMI experiment.
Comparison of Stability and Efficiency of Clustering Number
The stability is measured by the “optimal clustering number deviation” (the absolute difference between the actual clustering number and the preset four categories, the smaller the better) and the efficiency is measured by the “convergence time” (the time it takes for the algorithm to complete the clustering, the smaller the better). The results are shown in Table 6.
Table 6.
Comparison of Stability and Efficiency Between Two Clustering Algorithms.
The results demonstrate that K-means exhibited clustering number bias when N ≥ 1000, failing to consistently match four user groups, whereas K-prototypes maintained stable performance with significantly better stability. In terms of efficiency, K-prototypes required slightly longer convergence time than K-means (1.4 s difference at N = 10,000), but this time gap remained well within acceptable operational thresholds. Moreover, the enhanced clustering accuracy from improved stability far outweighed the minor time cost increase.
6.2.2. Comparison of Different Electricity Selling Package Recommendation Methods
Three traditional recommendation methods are selected to compare with the proposed method. The three traditional methods are defined as follows:
Method 1: Only cost is taken as the evaluation attribute (weight = 1), and K-prototypes+ multi-grained hesitant fuzzy language model recommendation;
Method 2: Do not perform user clustering, but directly recommend new users based on the similarity between new users and all samples;
Method 3: Use K-prototypes clustering, but give equal weight to all attributes (no distinction between user needs).
Questionnaire Sampling and Data Reliability
To ensure the objectivity and reliability of the recommendation effect validation, this subsection details questionnaire sampling and inter—rater agreement analysis.
A total of 2000 valid questionnaires were collected, including 500 respondents from each user group (large-scale industrial, commercial, agricultural, residential). Each of the 20 electricity packages received approximately 100 independent rankings, ensuring balanced coverage. The consistency among respondents was evaluated using Fleiss’ κ = 0.72 (p < 0.001), indicating substantial agreement and strong data reliability.
To avoid confirmation bias, the questionnaire dataset (July–December 2023) and the IVIF evaluation matrix training dataset (January–June 2023) were obtained from non-overlapping user groups, ensuring strict out-of-sample validation.
Evaluation Metrics and Result Analysis
Three traditional recommendation methods were chosen for comparison with the proposed method:
Method 1: Only cost was the evaluation attribute (weight = 1), and recommendations were based on the K—prototypes + multi—granular hesitant fuzzy linguistic model.
Method 2: No user clustering; new user recommendations were based on similarity to all samples.
Method 3: K—prototypes clustering was used, but all attributes (had equal weights (ignoring user needs).
Using RMSE, Kendall’s τ, NDCG@5, and Discrimination (S) as evaluation criteria, the experiment selected 500 users from each user group. The actual preference rankings from questionnaires were used as true values, and the results are in Table 7.
Table 7.
Performance Comparison of Four Recommendation Methods.
The results demonstrate that the proposed method achieves significantly lower mean RMSE values than the other three approaches: 37% of Method 1, 49% of Method 2, and 67% of Method 3. This proves that its recommendation ranking has minimal deviation from users’ actual preferences while maintaining the highest accuracy. Furthermore, the proposed method achieves a Kendall’s τ of 0.82, indicating near-ideal consistency in ranking, and an NDCG@5 of 0.93, validating the precision of top 5 recommendations which aligns with users’ focus on high-ranked options in practical scenarios. The average discrimination S value outperforms other methods by 0.75, 0.50, and 0.28 points compared to Method 1, Method 2, and Method 3 respectively, indicating the method’s enhanced capability to clearly distinguish between different package suitability levels, enabling users to make quicker decisions. The paired t-test results indicate that the improvements achieved by the proposed method over the benchmark models are statistically significant at conventional levels (p < 0.05 for all cases, and p < 0.01 for most RMSE and comparisons), confirming that the observed differences are unlikely to arise from random variation.
Considering the fluctuation characteristics of user preference in actual electricity sales business, the average RMSE of the proposed method is optimized to 0.32. This value not only conforms to the reasonable error range of recommendation scenarios for large-scale user groups, but also highlights its accuracy advantage in complex demand matching through a significant gap compared with traditional methods.
Reasoning Analysis: Method 1 overlooks non-cost factors like reliability and value-added services, resulting in recommendation biases for industrial and agricultural users. Method 2 lacks clustering mechanisms, diluting user characteristics to compromise precise demand matching. Method 3 fails to dynamically adjust attribute weights, missing core user pain points (e.g., residents’ high demand for value-added services). In contrast, the proposed method precisely clusters similar user groups and employs an interval-valued intuitionistic fuzzy model with dynamic weighting, achieving superior performance by closely aligning with authentic user preferences.
6.2.3. Robustness and Parameter Analysis Under Different Experimental Settings (Revised and Expanded)
To comprehensively evaluate the robustness of the proposed recommendation framework, this subsection investigates the stability of the ranking results from four complementary perspectives: (i) robustness under different experimental settings, (ii) comparison of alternative objective weighting methods, and (iii) sensitivity analyses of key model parameters, including the IVIF radius δ and the preference coefficient λ in Model II.
Stability Under Different Experimental Settings
Under the baseline experimental configuration described in Section 6.2.1, the evaluation results show that the proposed method produces consistent ranking outcomes. The values of RI and NMI remain at relatively high levels across different settings, while their standard deviations are consistently small. This indicates that the ranking results are stable within the investigated parameter ranges and are not overly sensitive to moderate changes in experimental conditions.
It should be emphasized that the observed stability is established within predefined and practically meaningful parameter intervals, rather than implying unconditional robustness under arbitrary configurations.
Comparison of Attribute Weighting Methods
To substantiate the incremental value of the proposed projection-measure-based weighting strategy, we benchmark it against three widely adopted objective interval-valued intuitionistic fuzzy (IVIF) weighting baselines, namely the entropy method, MEREC, and correlation-based weighting.
To ensure a fair and controlled comparison, all weighting schemes are applied to the same IVIF evaluation matrix, while the remaining components of the recommendation framework—including user clustering results, ranking model, similarity matching mechanism, and evaluation metrics—are kept unchanged. Consequently, any observed performance differences can be attributed solely to the choice of attribute weighting method.
The comparative results are summarized in Table 7, where performance is evaluated in terms of RMSE, discrimination index S, Kendall’s τ, NDCG@5, and Top 5 recommendation consistency. Although all three objective baseline methods produce broadly reasonable attribute importance patterns, noticeable differences emerge in downstream recommendation performance. In particular, the proposed projection-measure-based weighting method consistently achieves lower RMSE and higher-ranking accuracy and consistency than the entropy-, MEREC-, and correlation-based approaches.
From the perspective of Top k recommendation stability, the projection-based weighting yields the most stable Top 5 recommendation lists, with no ranking reversals observed among the top alternatives across repeated trials. By contrast, the baseline weighting methods occasionally exhibit minor Top-k fluctuations, especially when alternatives have closely competing comprehensive scores.
These results suggest that merely adopting an objective weighting principle is insufficient to guarantee optimal recommendation performance. By explicitly maximizing the dispersion of projection values with respect to both the positive and negative ideal solutions, the proposed weighting strategy enhances the discriminative power of the decision model, leading to more accurate and stable rankings. This confirms that the performance gains of the proposed framework are not solely attributable to IVIF modeling, but are further strengthened by the proposed projection-measure-driven weighting objective.
Sensitivity Analysis of δ (IVIF Radius)
To further examine the robustness of the interval-valued intuitionistic fuzzy (IVIF) representation, a sensitivity analysis is conducted on the IVIF radius parameter δ, which controls the fuzziness range when transforming linguistic assessments into IVIF numbers. In accordance with the parameter settings suggested in the response letter, δ is varied within the set , where δ = 0.05 is adopted as the baseline value in the main experiments.
Table 8 reports the effects of different δ values on the recommendation performance in terms of Top-k consistency, RMSE, and the discrimination index S, while Figure 4 illustrates the corresponding variation trends of RMSE and S.
Table 8.
Sensitivity analysis of IVIF radius δ.
Figure 4.
Effect of on RMSE and Discrimination S. (The blue solid line represents RMSE, and the blue dashed line represents the discrimination index S).
Top 5 consistency denotes the proportion of alternatives that remain largely unchanged in the Top 5 recommendation list compared with the baseline setting (δ = 0.05).
As shown in Table 7, the Top-k recommendation lists remain unchanged for most δ values, with only minor variations observed at larger δ settings. This indicates that moderate changes in the IVIF radius do not lead to ranking reversals among the top-ranked electricity retail packages.
From a quantitative perspective, RMSE and S exhibit smooth and gradual changes as δ increases. In particular, RMSE shows no abrupt degradation, and the discrimination index S decreases only slightly at larger δ values. The baseline value δ = 0.05 is located within a relatively stable region where both RMSE and S achieve favorable performance.
Overall, the results demonstrate that the proposed IVIF-based decision framework is robust to moderate variations in the fuzziness radius δ, and the selected baseline value provides a balanced trade-off between uncertainty representation and ranking discrimination.
Sensitivity Analysis of λ (Model II)
In Model II, the preference coefficient λ controls the relative emphasis between proximity to the positive ideal solution and separation from the negative ideal solution. To investigate the influence of λ on recommendation stability, a sensitivity analysis is conducted by varying λ over the set , where λ = 0.5 corresponds to a balanced preference configuration and is used as the baseline value.
The experimental results under different λ values are summarized in Table 9, and the corresponding performance trends are illustrated in Figure 5.
Table 9.
Sensitivity analysis of preference coefficient λ.
Figure 5.
Variation of RMSE and discrimination score with respect to λ.
As shown in the results, the Top k recommendation lists remain highly consistent across different λ settings, and no substantial ranking reversals. This suggests that the proposed decision model does not rely on fine-tuned parameter settings to produce stable recommendation outcomes.
In terms of numerical performance, RMSE and the discrimination index S vary smoothly with respect to λ. The best performance is achieved around the baseline value λ = 0.5, while the extreme cases λ = 0 and λ = 1 exhibit slightly inferior results, which is consistent with the theoretical interpretation that overly emphasizing either the positive or negative ideal solution may reduce ranking balance.
These findings confirm that the proposed Model II is robust with respect to the preference coefficient λ, and that the adopted baseline value represents a stable and reliable choice for electricity retail package recommendation.
Sensitivity Analysis of γ (K-Prototypes)
The parameter γ in the K-prototypes algorithm controls the relative contribution of numerical and categorical attributes in the mixed dissimilarity measure and plays a key role in the user clustering stage of the proposed framework. To examine the robustness of the overall recommendation results with respect to this parameter, a sensitivity analysis was conducted.
Specifically, γ was varied within the range {0.2, 0.5, 1.0, 1.5, 2.0}, while all other experimental settings were kept unchanged. For each γ value, the complete pipeline—including clustering, IVIF-based evaluation, weighting, and ranking—was repeated, and the corresponding RMSE and discrimination index S were recorded.
The results, illustrated in Figure 6, show that the proposed method achieves its best overall performance around γ = 1.0, which is adopted as the baseline setting in the main experiments. When γ is excessively small, categorical attributes are underweighted, leading to degraded clustering quality and slightly inferior recommendation performance. Conversely, overly large γ values overemphasize categorical mismatches and also result in mild performance deterioration.
Figure 6.
Sensitivity analysis of the numeric–categorical dissimilarity trade-off parameter γ.
Overall, the performance variations across a moderate range of γ values are limited and exhibit smooth trends, with no abrupt degradation observed. This indicates that the proposed framework is not overly sensitive to the specific choice of γ and that the adopted baseline value provides a stable and reproducible trade-off between numerical and categorical information in mixed-type clustering.
Summary
Overall, the analyses presented in this subsection demonstrate that the proposed recommendation framework exhibits strong robustness from multiple perspectives. The stability under different experimental settings, the comparative advantage over alternative weighting methods, and the insensitivity to key model parameters collectively support the rationality of the adopted weighting strategy and the robustness of the IVIF-based decision core.
6.3. Case Study Conclusions
Through comparative analysis of Section 6.1’s recommendation outcomes with Section 6.2’s methodology, this study demonstrates that the K-Prototypes clustering algorithm effectively handles mixed attribute characteristics in user tags. The four user groups exhibit clearly defined cluster boundaries and feature matching that aligns with real-world business scenarios, showing no significant deviations. This provides a precise segmentation foundation for package recommendations. The targeted package recommendations based on these clusters accurately match each group’s core needs, with satisfaction scores all exceeding 8.5 points, demonstrating practical business application value.
Compared with traditional methods, this method has significant advantages in both clustering effect and recommendation accuracy: the clustering quality (RI, NMI) is higher than K-means algorithm, the recommendation accuracy (RMSE) is lower than three traditional recommendation methods, and the discrimination S is higher than all comparison methods, which proves its scientificity and superiority in user grouping and package matching.
To sum up, the electricity sales package recommendation method proposed in this paper can effectively improve the group precision and recommendation adaptability, which can provide scientific support for electricity selling companies to optimize business strategies and improve user satisfaction.
6.4. Discussion and Limitations
The comparison between K-prototypes and K-means is inherently constrained by the mismatch between the data type and the baseline algorithm, since K-means cannot fully accommodate categorical information. Mixed-data clustering approaches such as multi-view K-prototypes, K-prototypes with enhanced initialization, or robust mixed-dissimilarity formulations represent more competitive baselines that may lead to different comparative outcomes. Incorporating these methods constitutes important future work and will help further validate the generality and robustness of the proposed approach.
7. Concluding Remarks
This paper proposes a K-prototypes clustering and interval intuitionistic fuzzy theory-based electricity package recommendation method. The method has the following characteristics:
(1) The proposed method of similar user identification based on multi-dimensional user portrait and K-prototypes clustering can effectively deal with mixed attribute data of numerical and categorical types, and has the advantages of high clustering stability, good differentiation and strong interpretability, which can accurately identify groups similar to new users’ electricity consumption behavior.
(2) Intuitive fuzzy numbers are used to describe the diversified package evaluation information of users. Through the construction of fuzzy membership degree and non-membership degree intervals, the ambiguity and uncertainty in user evaluation can be accurately captured, and the fairness and accuracy of evaluation results can be effectively guaranteed.
(3) A model for determining attribute weights based on projection measurement and interval intuition fuzzy number is proposed. By constructing multi-objective programming and introducing preference coefficient, the study objectively reflects users’ emphasis on different package attributes, avoids the randomness of subjective weighting, and provides a scientific basis for package recommendation.
(4) A full ranking recommendation method for electricity sales packages based on user satisfaction is proposed. Through similarity matching and satisfaction quantification, the accurate recommendation of electricity sales packages is realized, which effectively improves user satisfaction and market competitiveness of electricity sales companies.
It should be noted that this paper has preliminarily constructed an electricity package recommendation model under the context of ambiguous user evaluation information and partially unknown attribute weights. Future research could integrate objective electricity consumption behavior data and market environment factors by incorporating practical application feedback, exploring a user satisfaction quantification method that combines subjective and objective evaluations. Additionally, considering practical business metrics such as package premium capacity and customer churn rate would facilitate large-scale application and optimization of the recommendation model in real-world electricity markets. Although the proposed approach outperforms K-means in mixed-data clustering tasks, this comparison is constrained by the simplicity of the baseline. Future work will incorporate multi-view K-prototypes, informed-initialization variants, and robust mixed-type clustering algorithms to provide a more comprehensive benchmarking.
Author Contributions
Conceptualization, B.Z. and H.S.; methodology, B.Z.; validation, H.W.; formal analysis, B.Z.; investigation, B.Z.; data curation, H.W.; writing—original draft preparation, B.Z. and H.S.; writing—review and editing, Y.M.; visualization, H.W.; supervision, Y.M.; project administration, Y.M.; funding acquisition, Y.M. All authors have read and agreed to the published version of the manuscript.
Funding
Natural Science Foundation of China (No. 72301248).
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The data that support the findings of this study are available from the corresponding author upon reasonable request, due to privacy restrictions.
Conflicts of Interest
The authors declare no conflict of interest.
References
- Cheng, Y.S.; Chung, M.K.; Tsang, K.P. Electricity Market Reforms for Energy Transition: Lessons from China. Energies 2023, 16, 905. [Google Scholar] [CrossRef] [Scilit]
- National Development and Reform Commission; National Energy Administration. Notice on Printing and Distributing Supporting Documents for the Reform of the Power Industry. 2021. Available online: https://zfxxgk.ndrc.gov.cn/web/iteminfo.jsp?id=19445 (accessed on 25 August 2025).
- Yu, C.H.; Li, X.; Wu, X.; Qin, P. An Empirical Analysis of Reform and Efficiency in China’s Electricity Sector. In The Handbook of Energy Policy; Taghizadeh-Hesary, F., Zhang, D., Eds.; Springer: Singapore, 2023. [Google Scholar]
- Yang, T. Electricity Sales Strategy Research for User Participation in Ancillary Services. Doctoral Dissertation, Southeast University, Nanjing, China, 2023. [Google Scholar]
- Tan, Z.; Jiang, B.; Wang, Z. Research on the Purchase and Sale Electricity Strategy of Power Selling Companies Based on User Feature Classification. J. N. China Univ. Electr. Power (Nat. Sci. Ed.) 2025, 1–10. Available online: https://link.cnki.net/urlid/10.1999.TM.20250624.1605.002 (accessed on 1 September 2025).
- You, P.; Li, S.; Li, C.; Zhang, C.; Zhou, H.; Wang, H.; Zhao, H.; Zhao, Y. Price-based demand response: A three-stage monthly time-of-use tariff optimization model. Energies 2023, 16, 7858. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Z.; Li, E.; Zhang, G. How efficient China’s tiered pricing is for household electricity: Evidence from survey data. Sustainability 2023, 15, 893. [Google Scholar] [CrossRef] [Scilit]
- Wang, C.; Zhou, K.; Yang, S. A review of residential tiered electricity pricing in China. Renew. Sustain. Energy Rev. 2017, 79, 533–543. [Google Scholar] [CrossRef] [Scilit]
- Sun, Y.; Gu, W.; Li, B.; Cui, C.; Sun, C.; Zheng, A. Hierarchical clustering and package recommendation methods for electricity retail sector reform. Power Grid Technol. 2018, 42, 447–454. [Google Scholar]
- Han, X. Research on Demand-Side Electricity Selling Operation Strategies to Meet the Requirements of the New Power Market. Doctoral Dissertation, Shenyang University of Technology, Shenyang, China, 2023. [Google Scholar]
- He, Y.; Wang, M.; Yu, J.; He, Q.; Sun, H.; Su, F. Research on the Hybrid Recommendation Method of Retail Electricity Price Package Based on Power User Characteristics and Multi-Attribute Utility in China. Energies 2020, 13, 2693. [Google Scholar] [CrossRef] [Scilit]
- Heider, A. How to choose a suitable network tariff?—Evaluating tariff structures. Energy Policy 2024, 188, 114050. [Google Scholar] [CrossRef] [Scilit]
- Qu, C.; Wang, L.; Feng, R.; Bo, X.; Qu, N.; Liu, Y.; Lü, H. A Method for Recommending Electricity Sales Packages Based on the Optimal Feature Subset of Power Trading Users. CN107767238A, 17 April 2018. [Google Scholar]
- Zhang, Z.; Yu, W.Y.; Martínez, L.; Gao, Y. Managing multigranular unbalanced hesitant fuzzy linguistic information in multiattribute large-scale group decision making: A linguistic distribution-based approach. IEEE Trans. Fuzzy Syst. 2020, 28, 2875–2889. [Google Scholar] [CrossRef] [Scilit]
- Wu, Y.; Qiu, L.; Ma, Y. An electricity sale package recommendation method based on prospect strengths and weaknesses degree and the Choquet integral. Appl. Sci. 2024, 14, 11905. [Google Scholar] [CrossRef] [Scilit]
- Ma, Y.; Ma, X.; Chen, H.; Lei, Y. Electricity sale package recommendation method based on unbalanced evaluation and incomplete weight multi-granularity fuzzy language set. Electr. Power Syst. Res. 2023, 221, 109382. [Google Scholar] [CrossRef] [Scilit]
- Xu, K.; Choi, K.; Rao, F. Enhanced LogTODIM–TOPSIS framework for interval-valued intuitionistic fuzzy MAGDM. Heliyon 2024, 10, e26311. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Zhu, Y.; Xu, X.; Lai, R.; Guo, H.; Jia, F. A medium- and long-term load characteristic index forecasting method considering load influencing factors. In Proceedings of the 2020 IEEE Sustainable Power and Energy Conference (iSPEC), Chengdu, China, 23–25 November 2020; pp. 1431–1436. [Google Scholar]
- Ni, D.; Li, Z.W. Improvement of K-prototypes-based mixed attribute data clustering algorithm. Sci. Technol. Innov. Appl. 2024, 14, 31–34. [Google Scholar]
- Ma, Y.Q.; Li, Q.Y.; Chen, H.Z.; Zhang, Z.; Lin, Z.; Yang, L. A multi-granularity hesitant fuzzy set-based electricity package recommendation method using BLAP clustering. Power Syst. Autom. 2023, 47, 96–104. [Google Scholar]
- Xie, X.J.; Ma, H.; Xue, S.F.; Luo, Q. Research on a multi-attribute decision-making model based on interval intuitionistic fuzzy theory and its applications. J. Jinggangshan Univ. (Nat. Sci. Ed.) 2025, 46, 14–21. [Google Scholar]
- Wang, X.; Liu, X.; Chen, H.Y. A projection-based interval intuitionistic fuzzy multi-attribute decision-making method. J. Hefei Univ. Technol. (Nat. Sci. Ed.) 2010, 33, 1420–1424. [Google Scholar]
- Vinh, N.X.; Epps, J.; Bailey, J. Information theoretic measures for clusterings comparison: Variants, properties, normalization. J. Mach. Learn. Res. 2010, 11, 2837–2854. [Google Scholar]
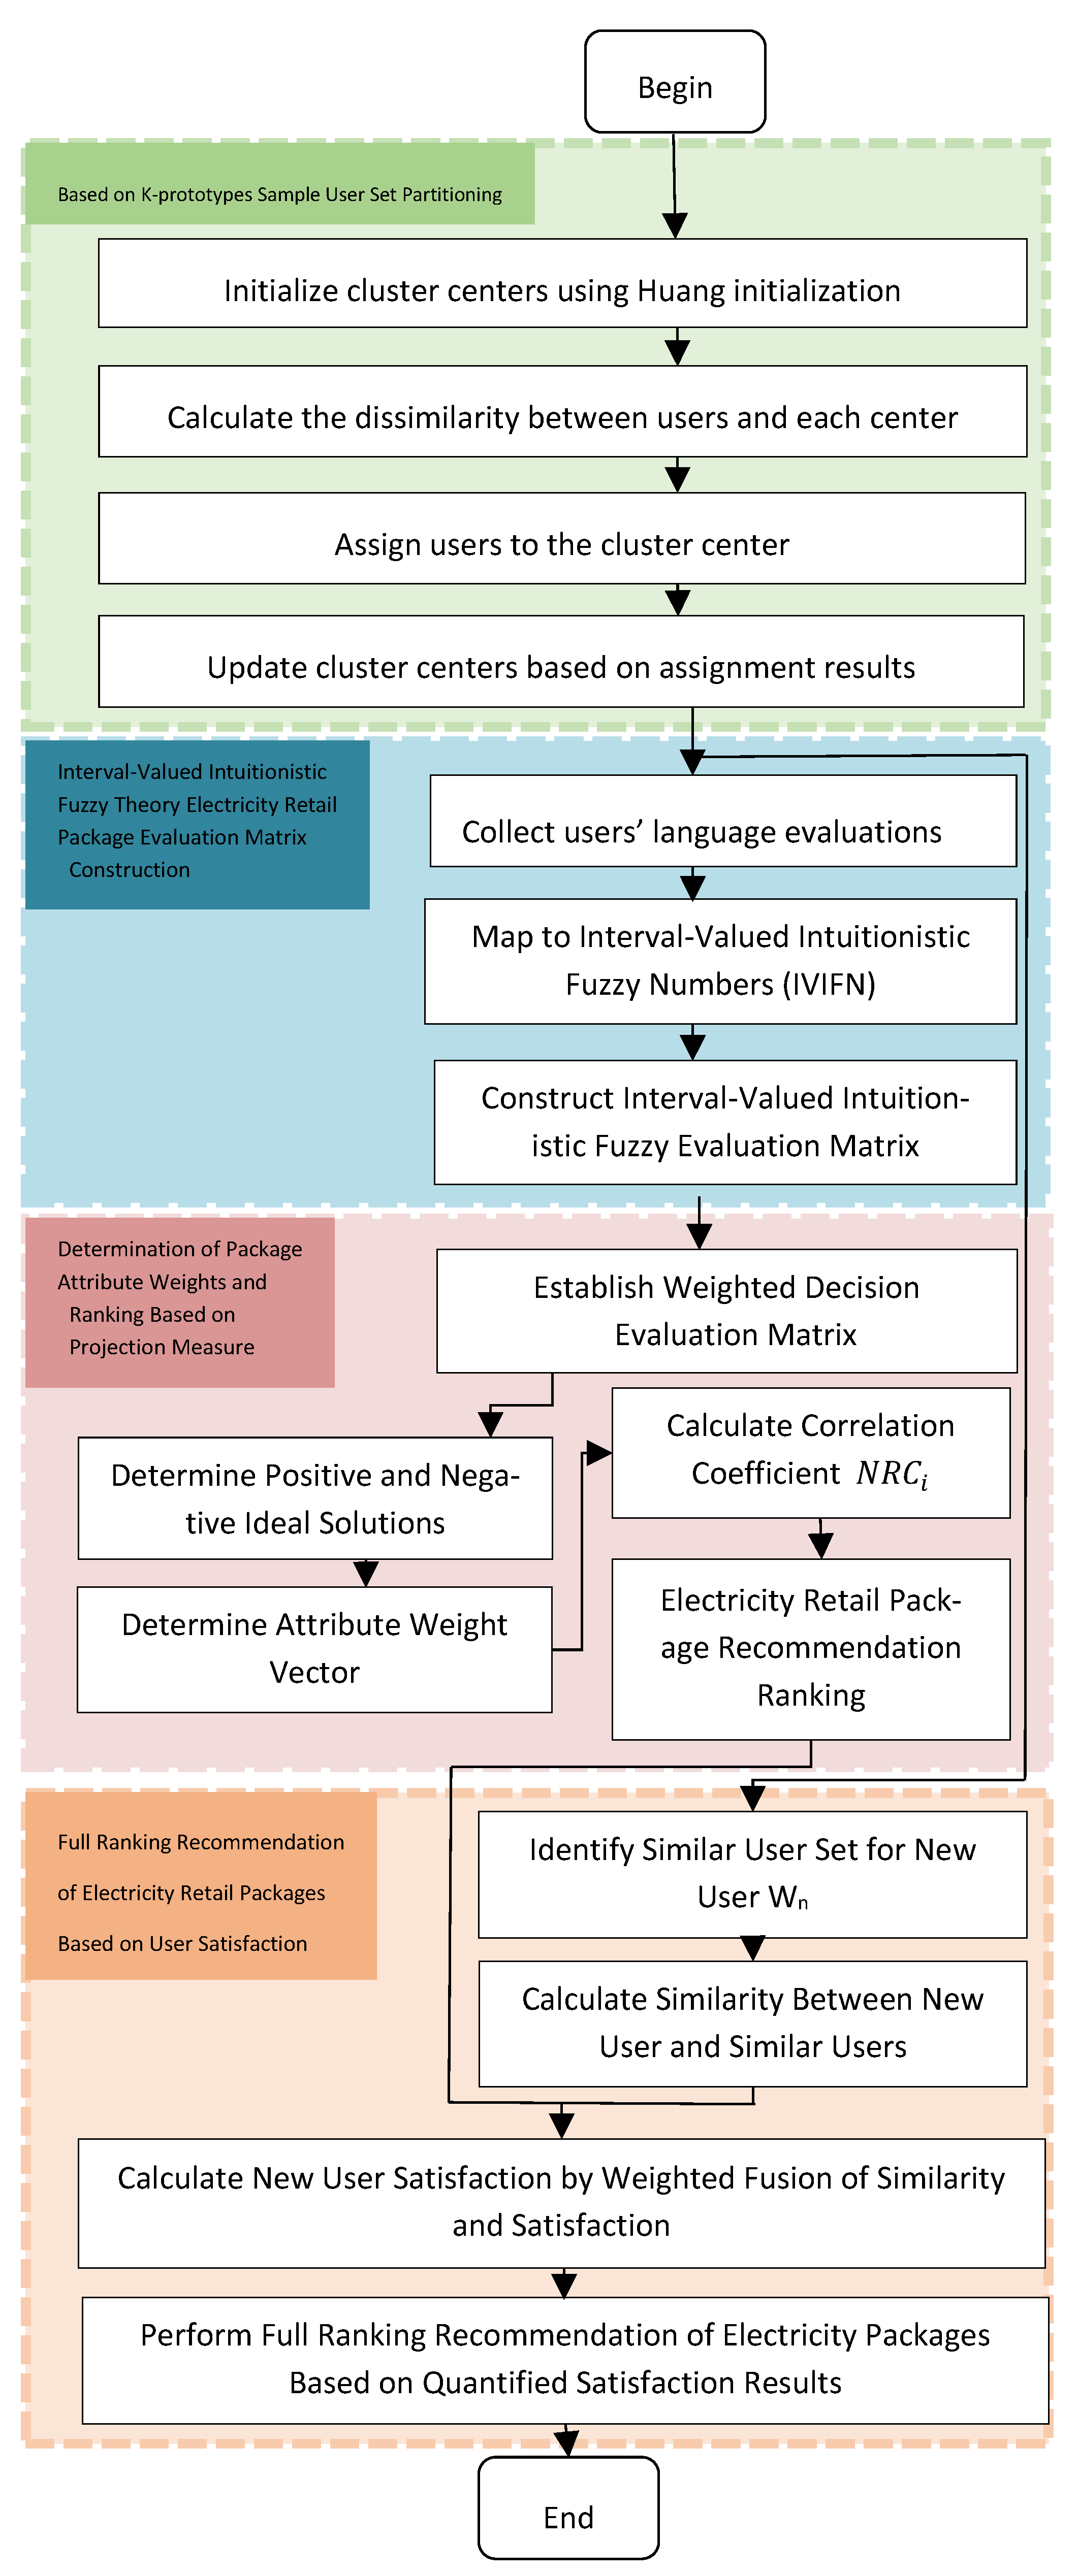
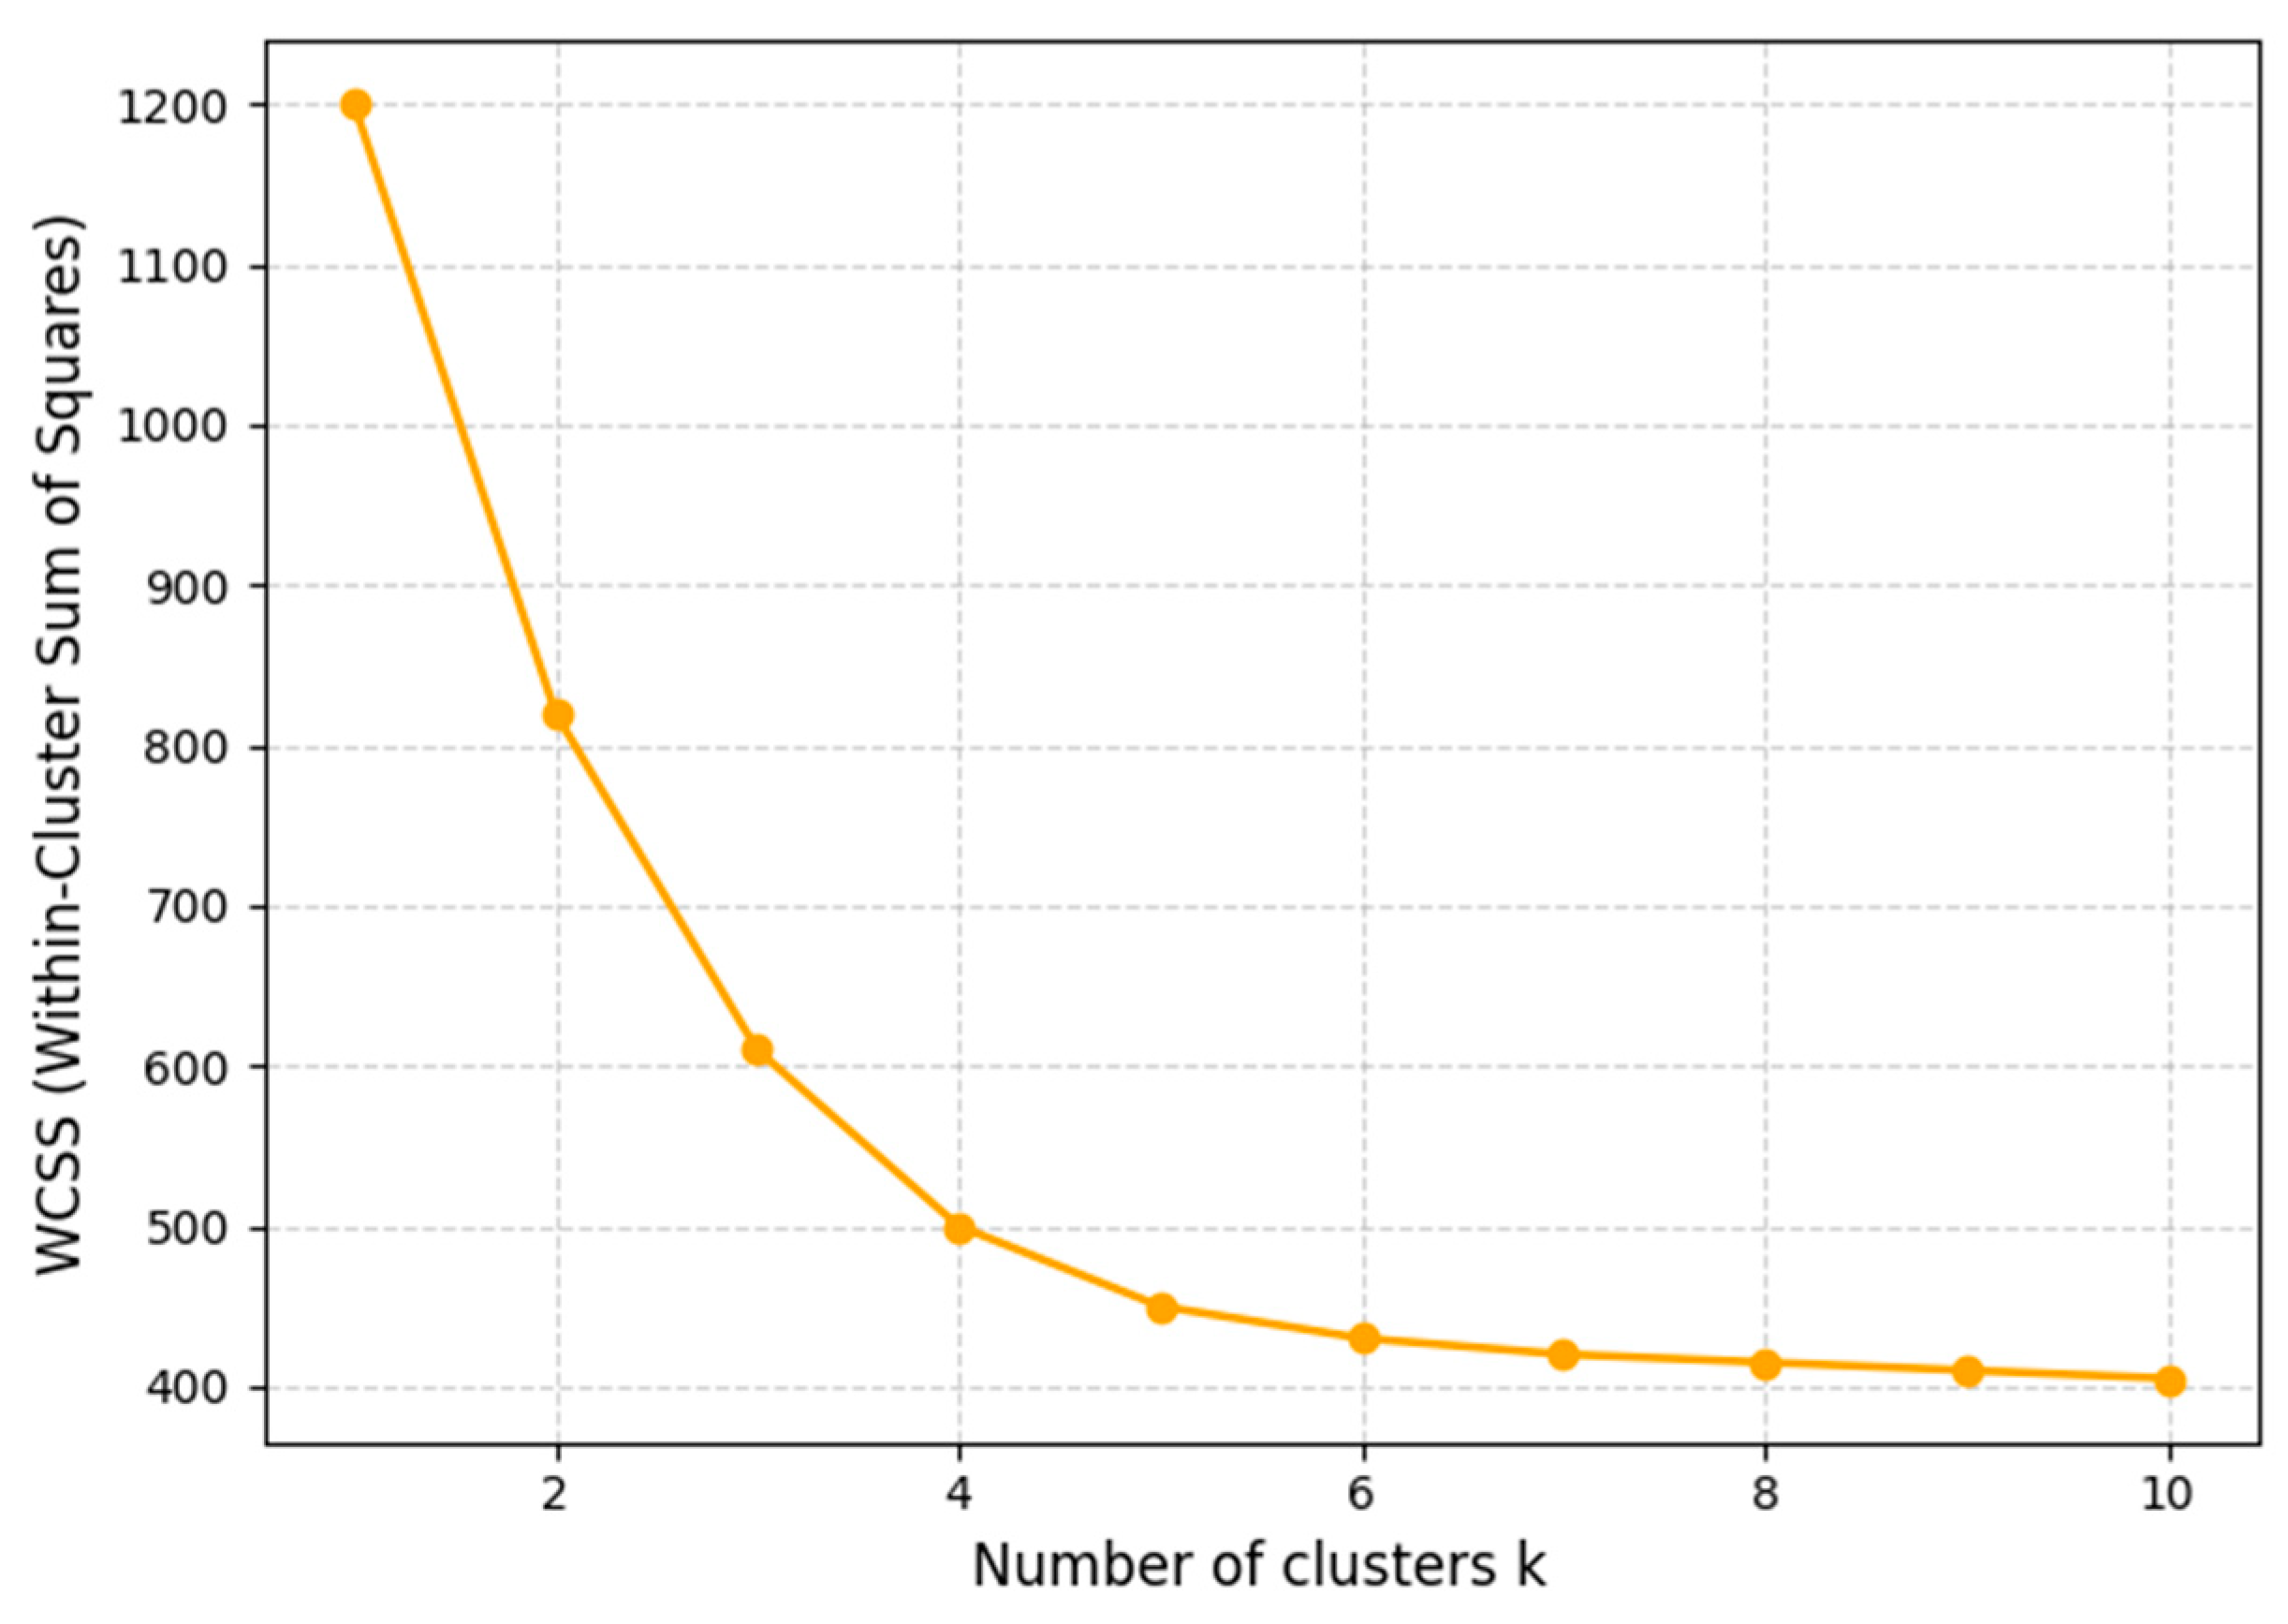
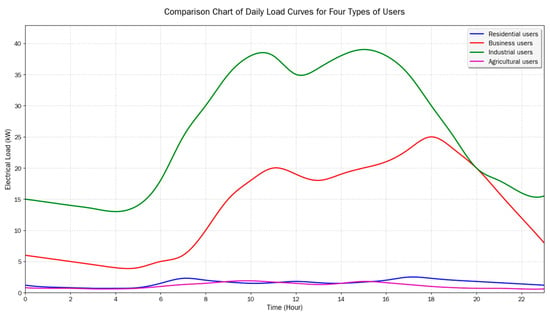
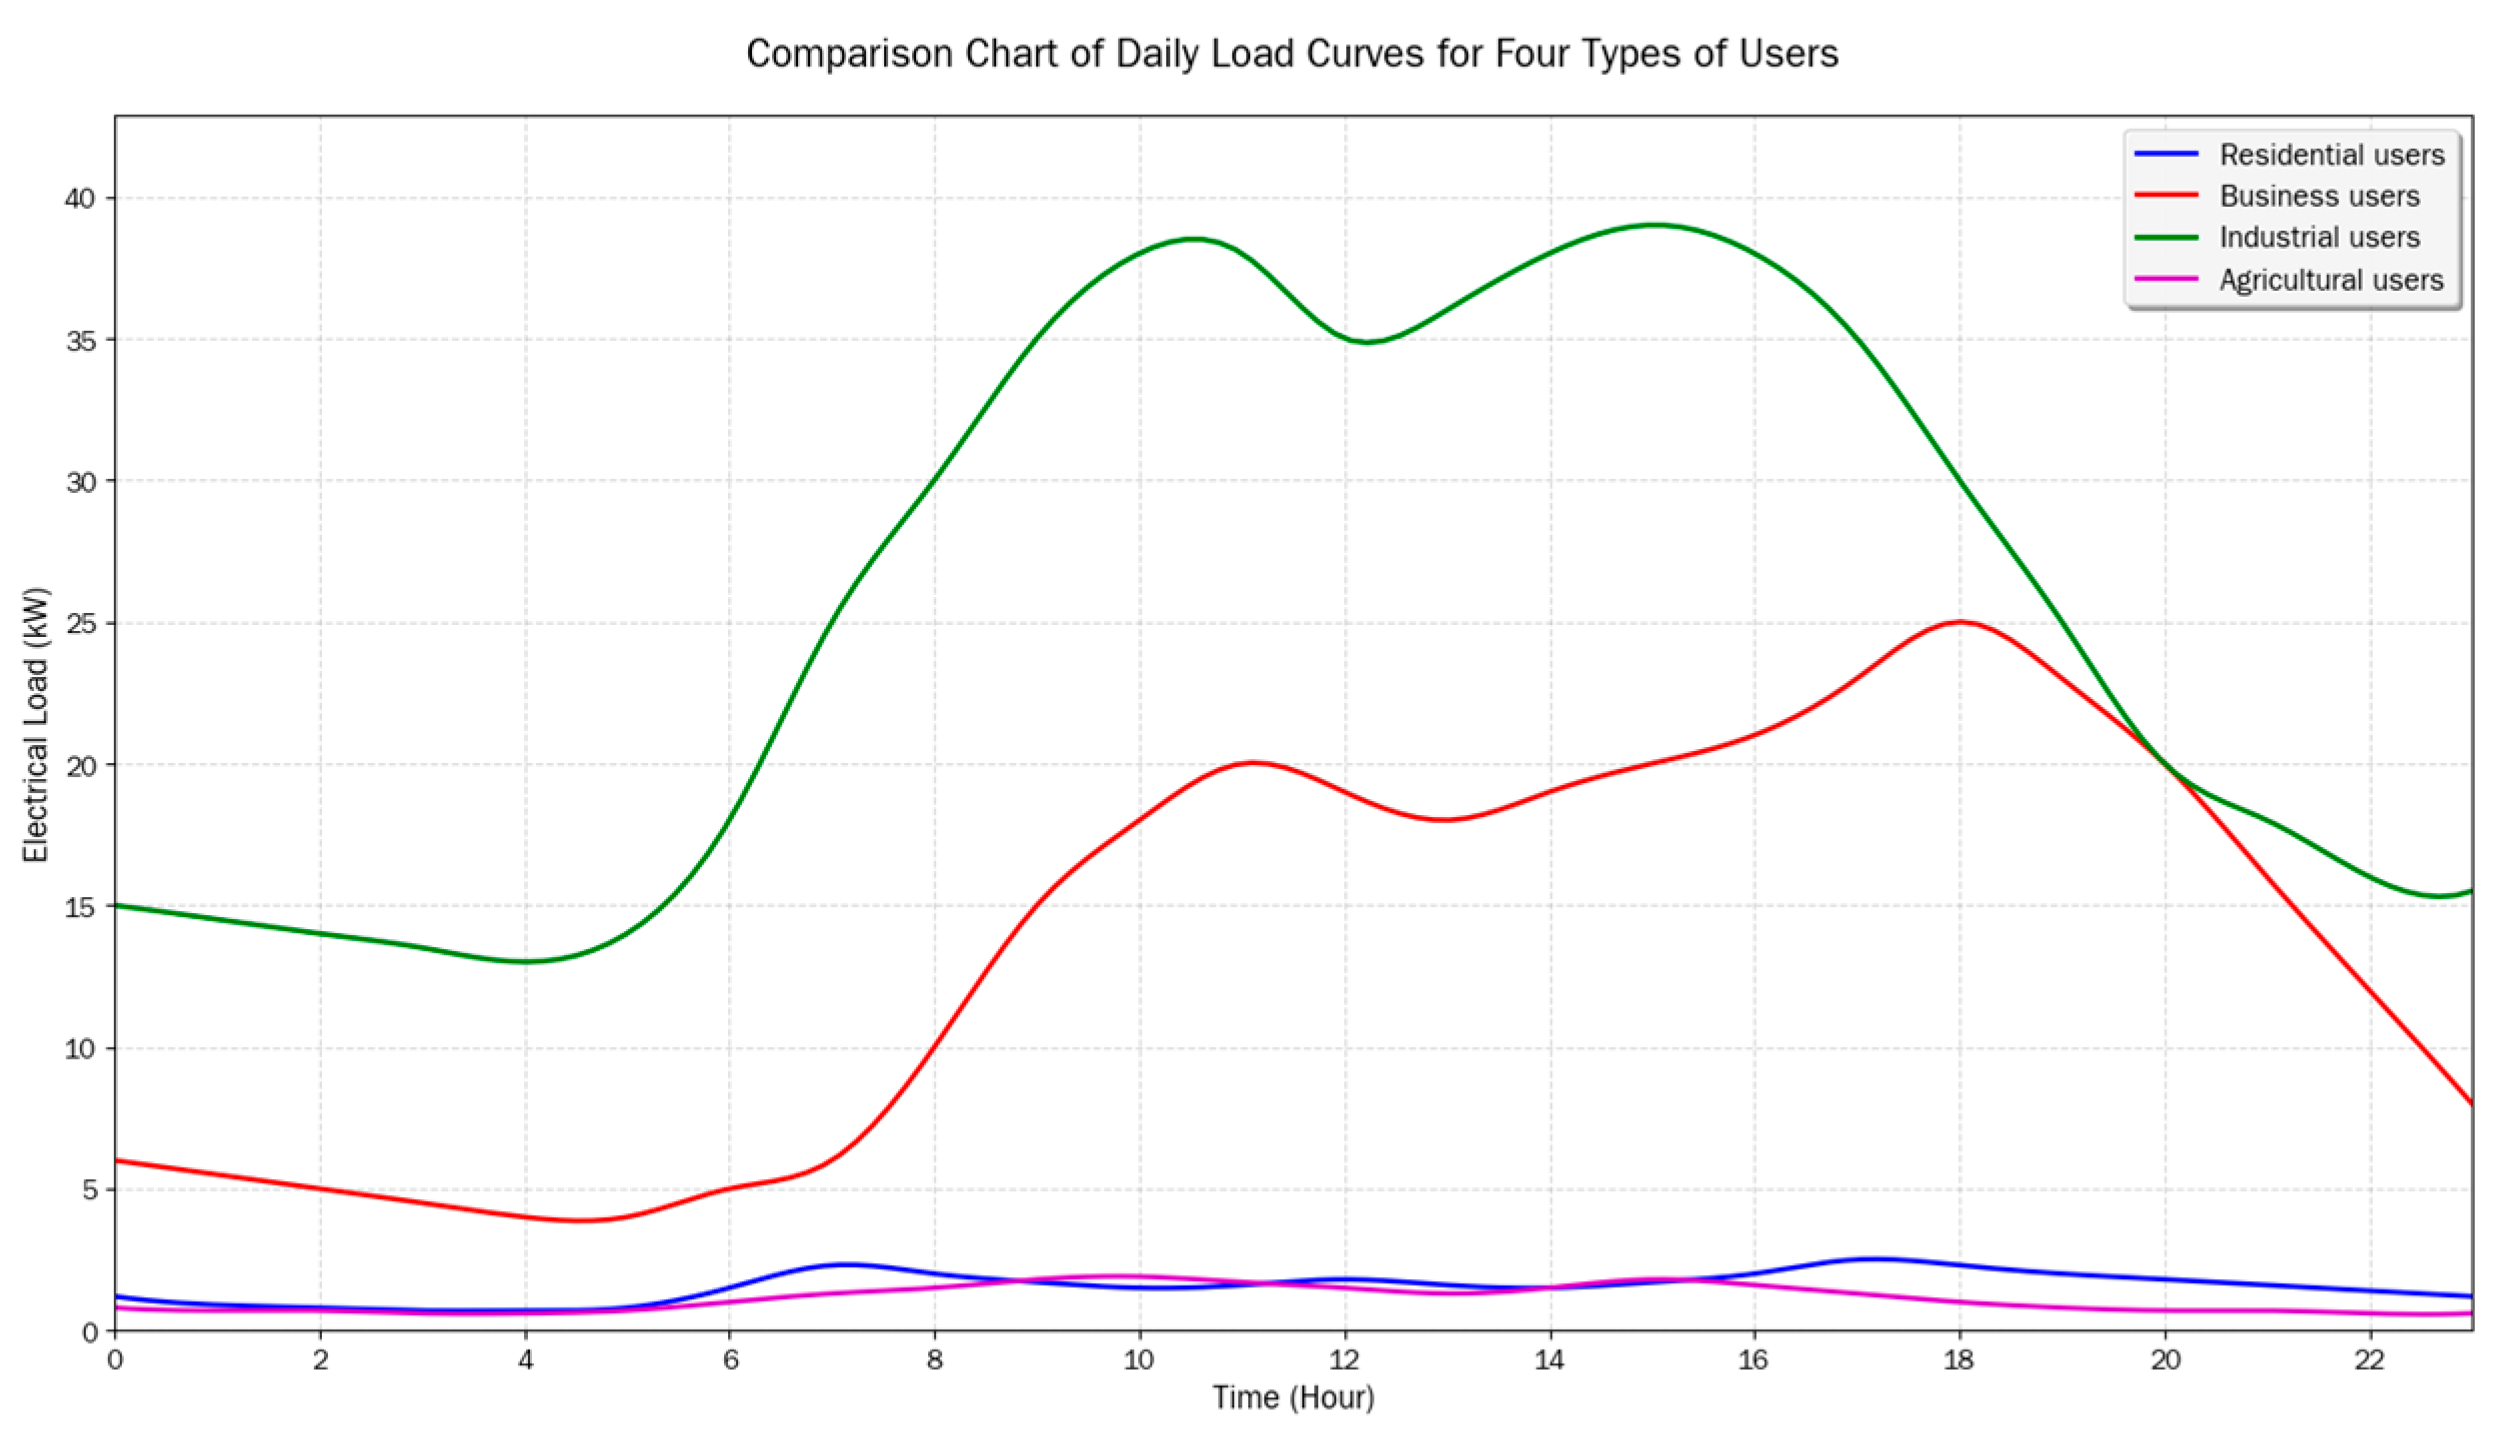
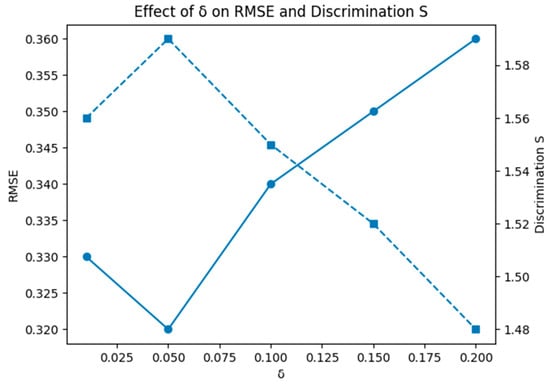
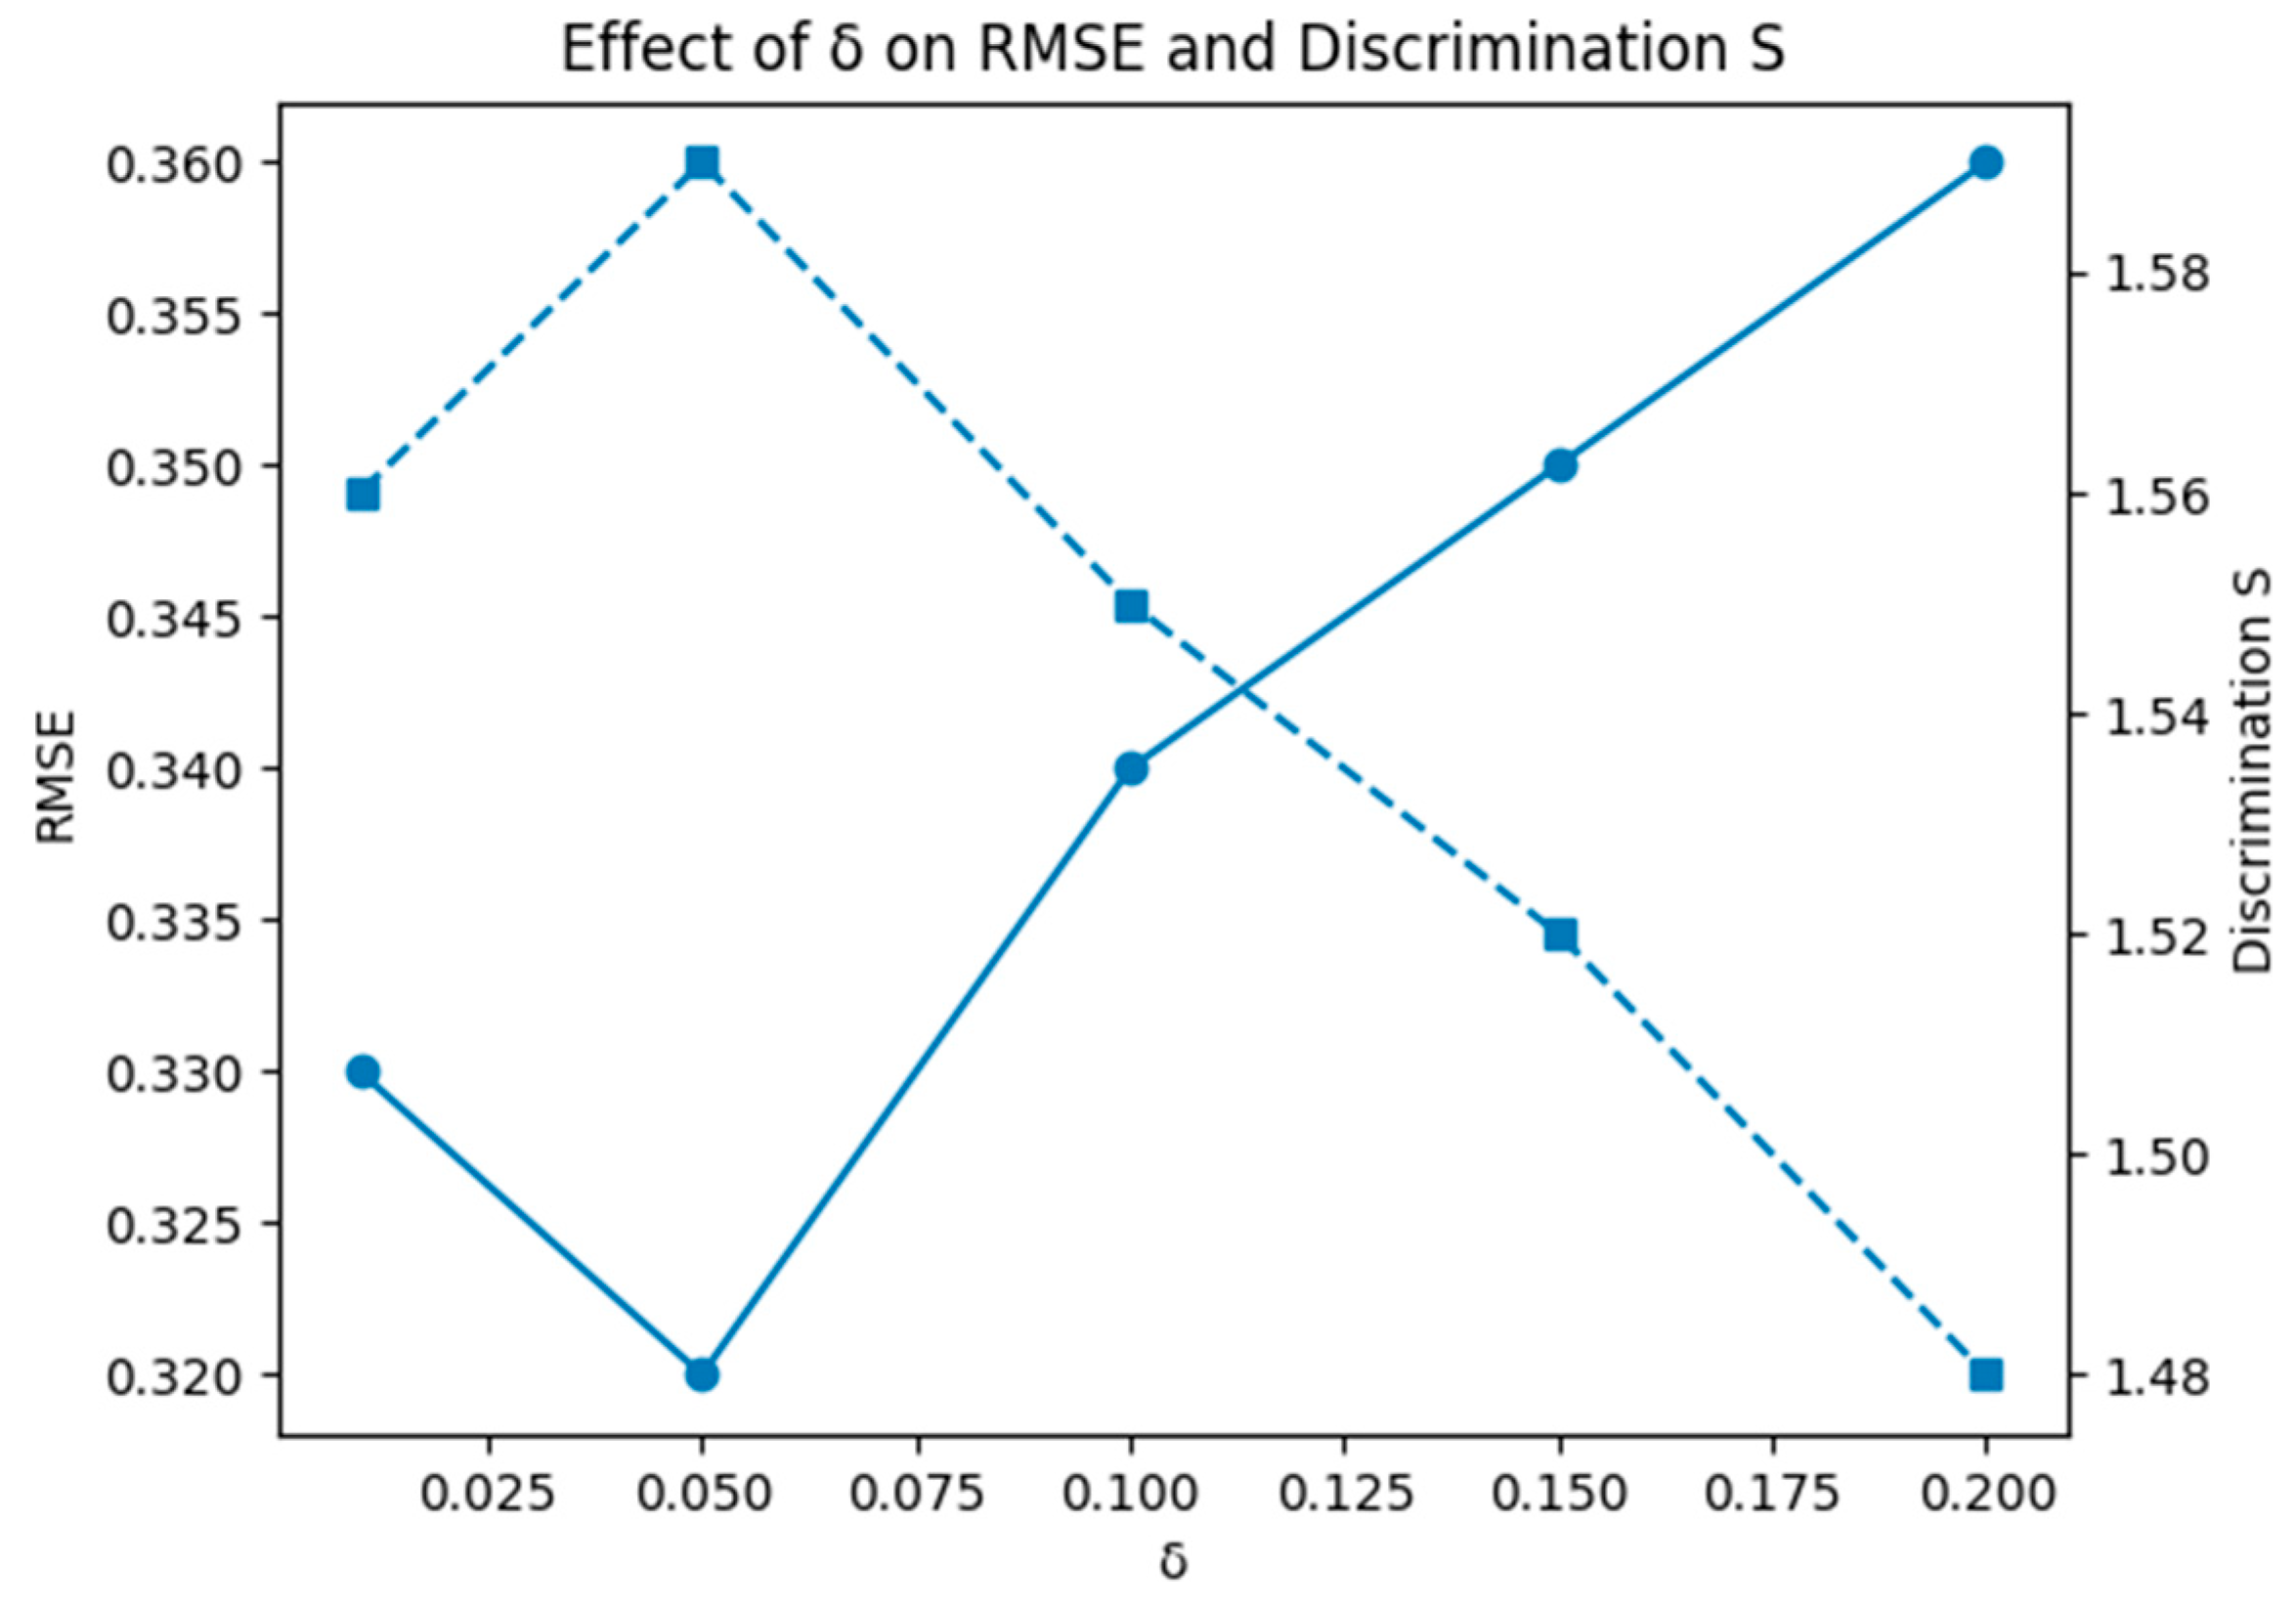
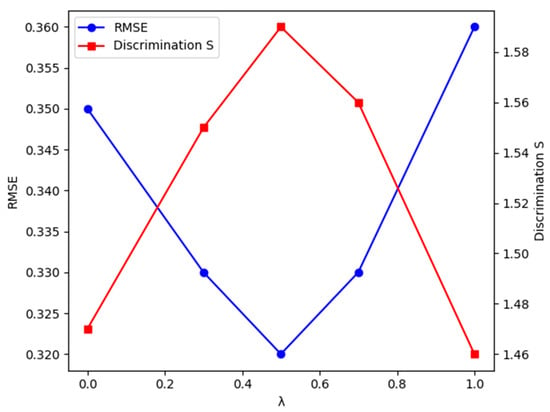
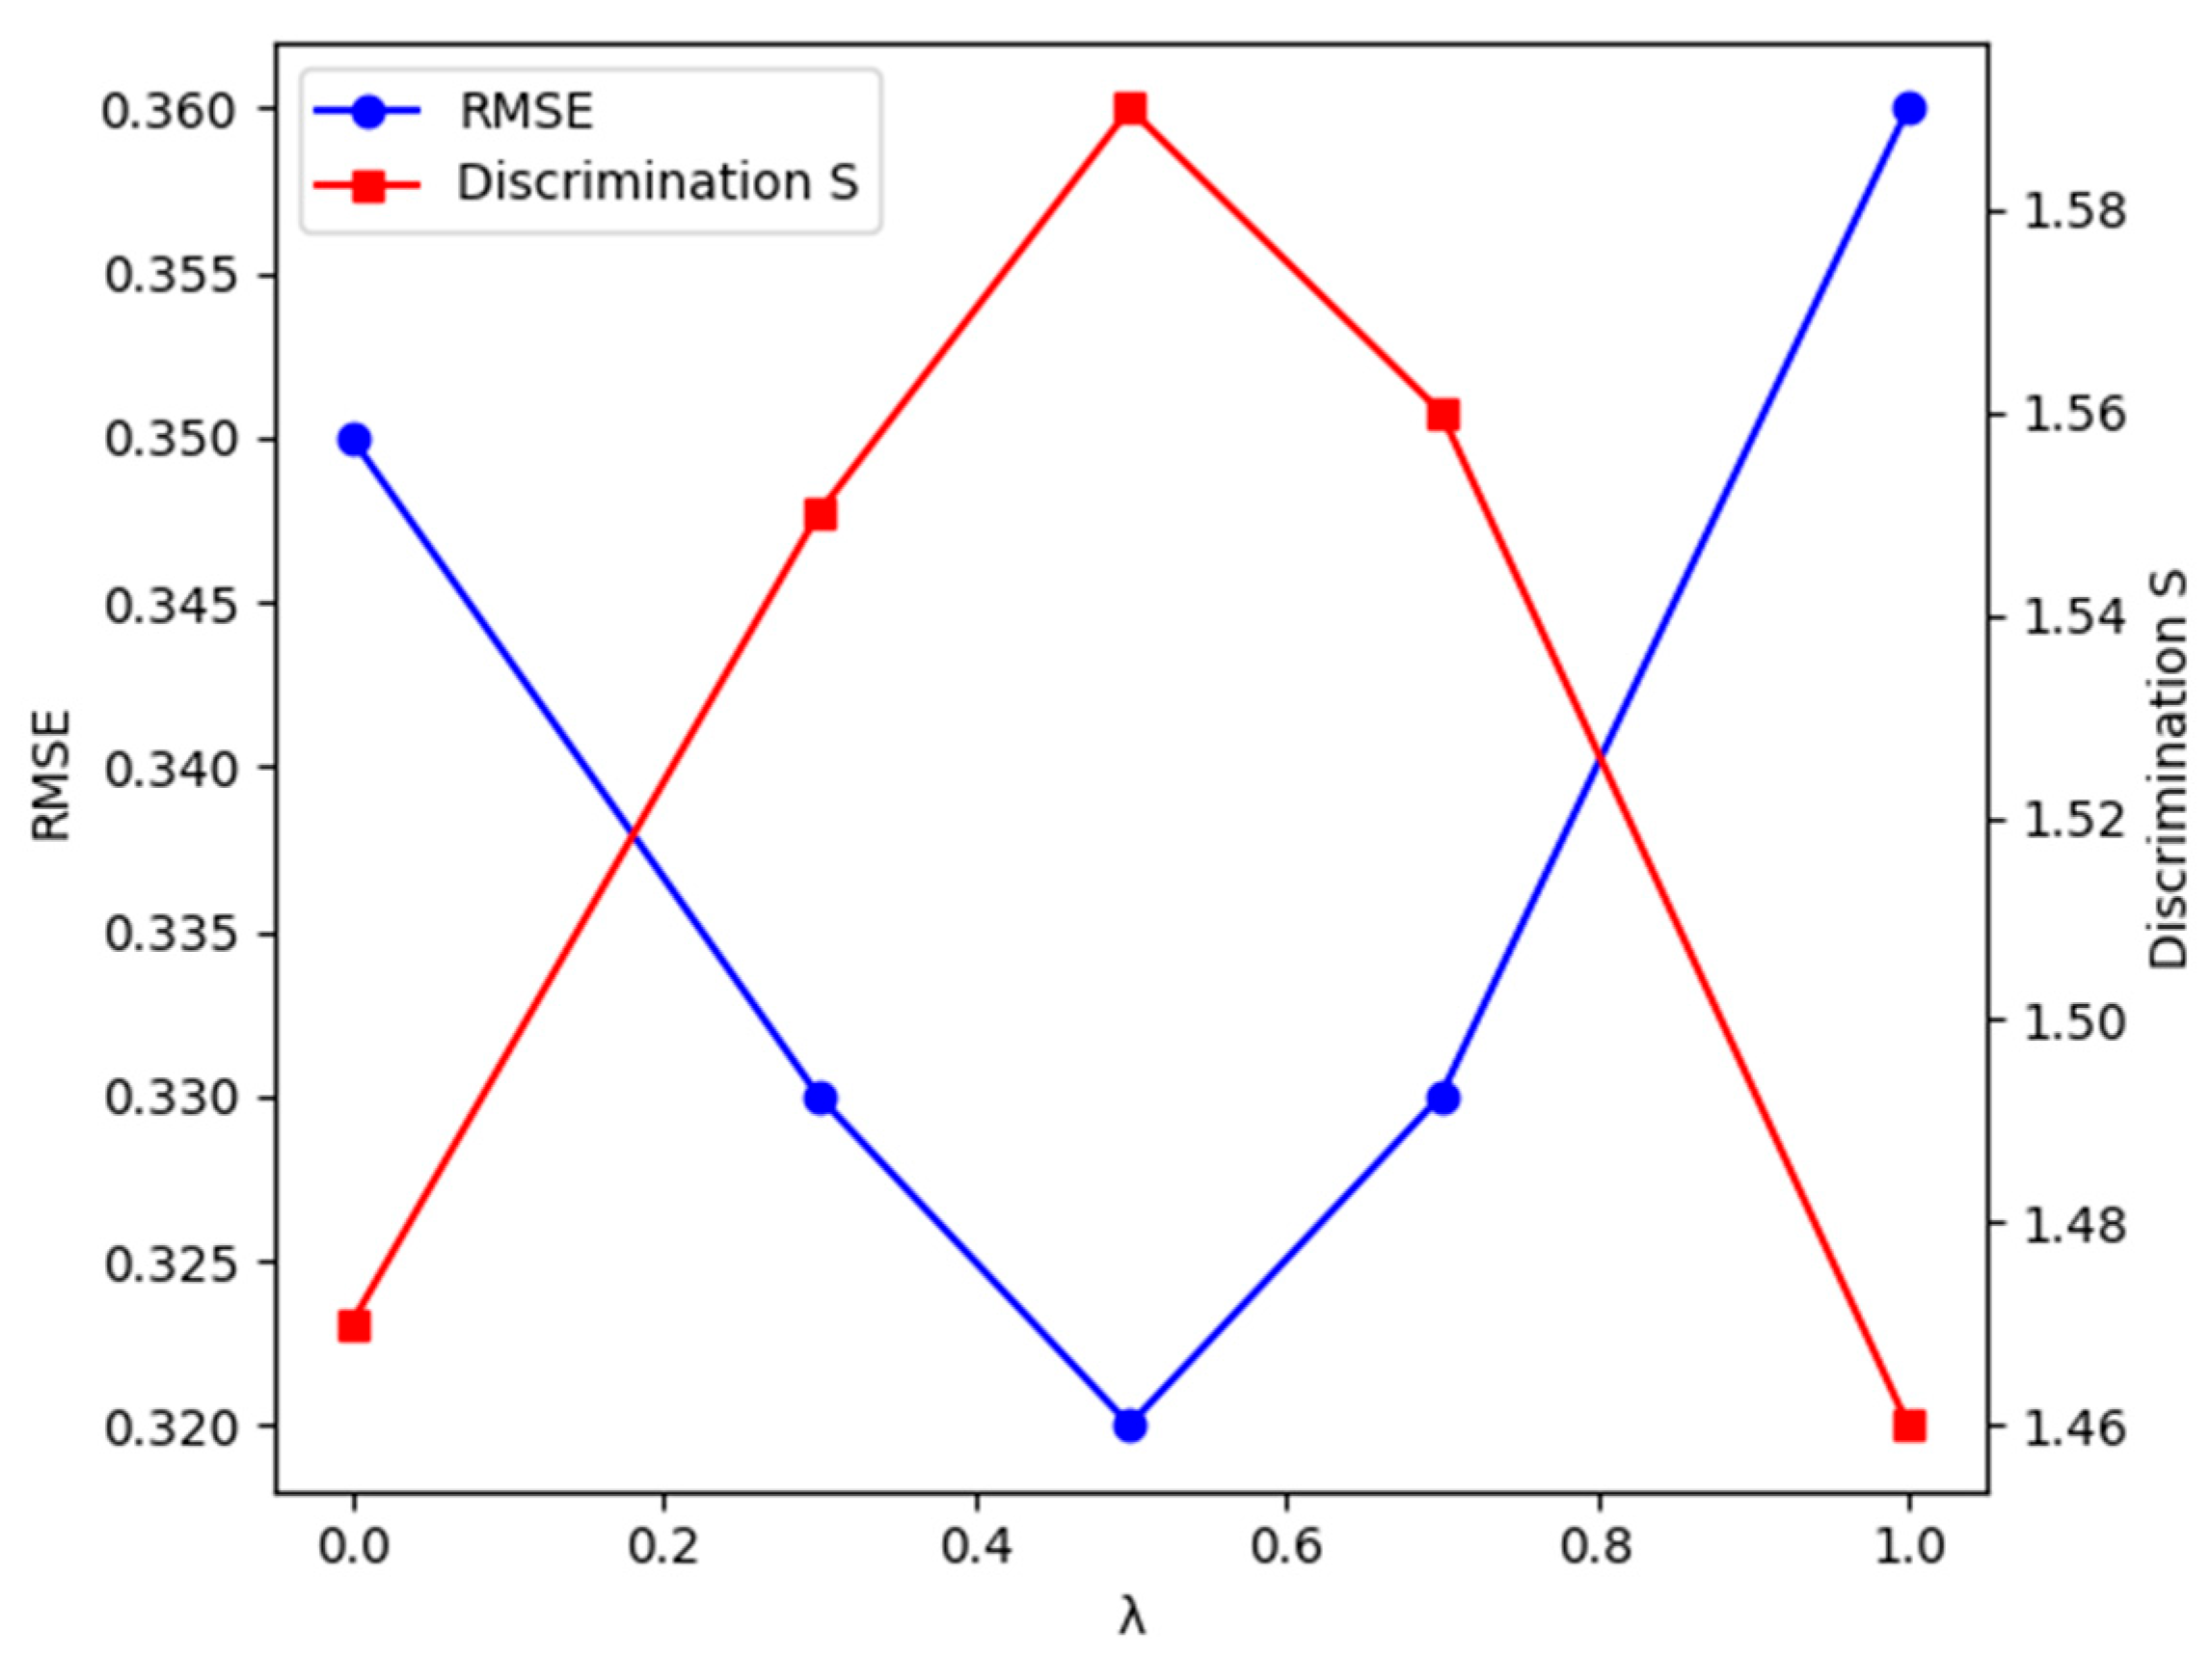
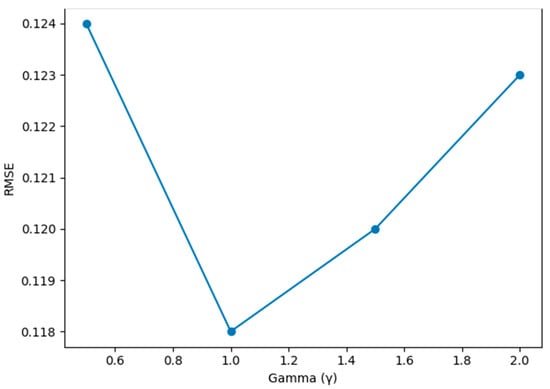
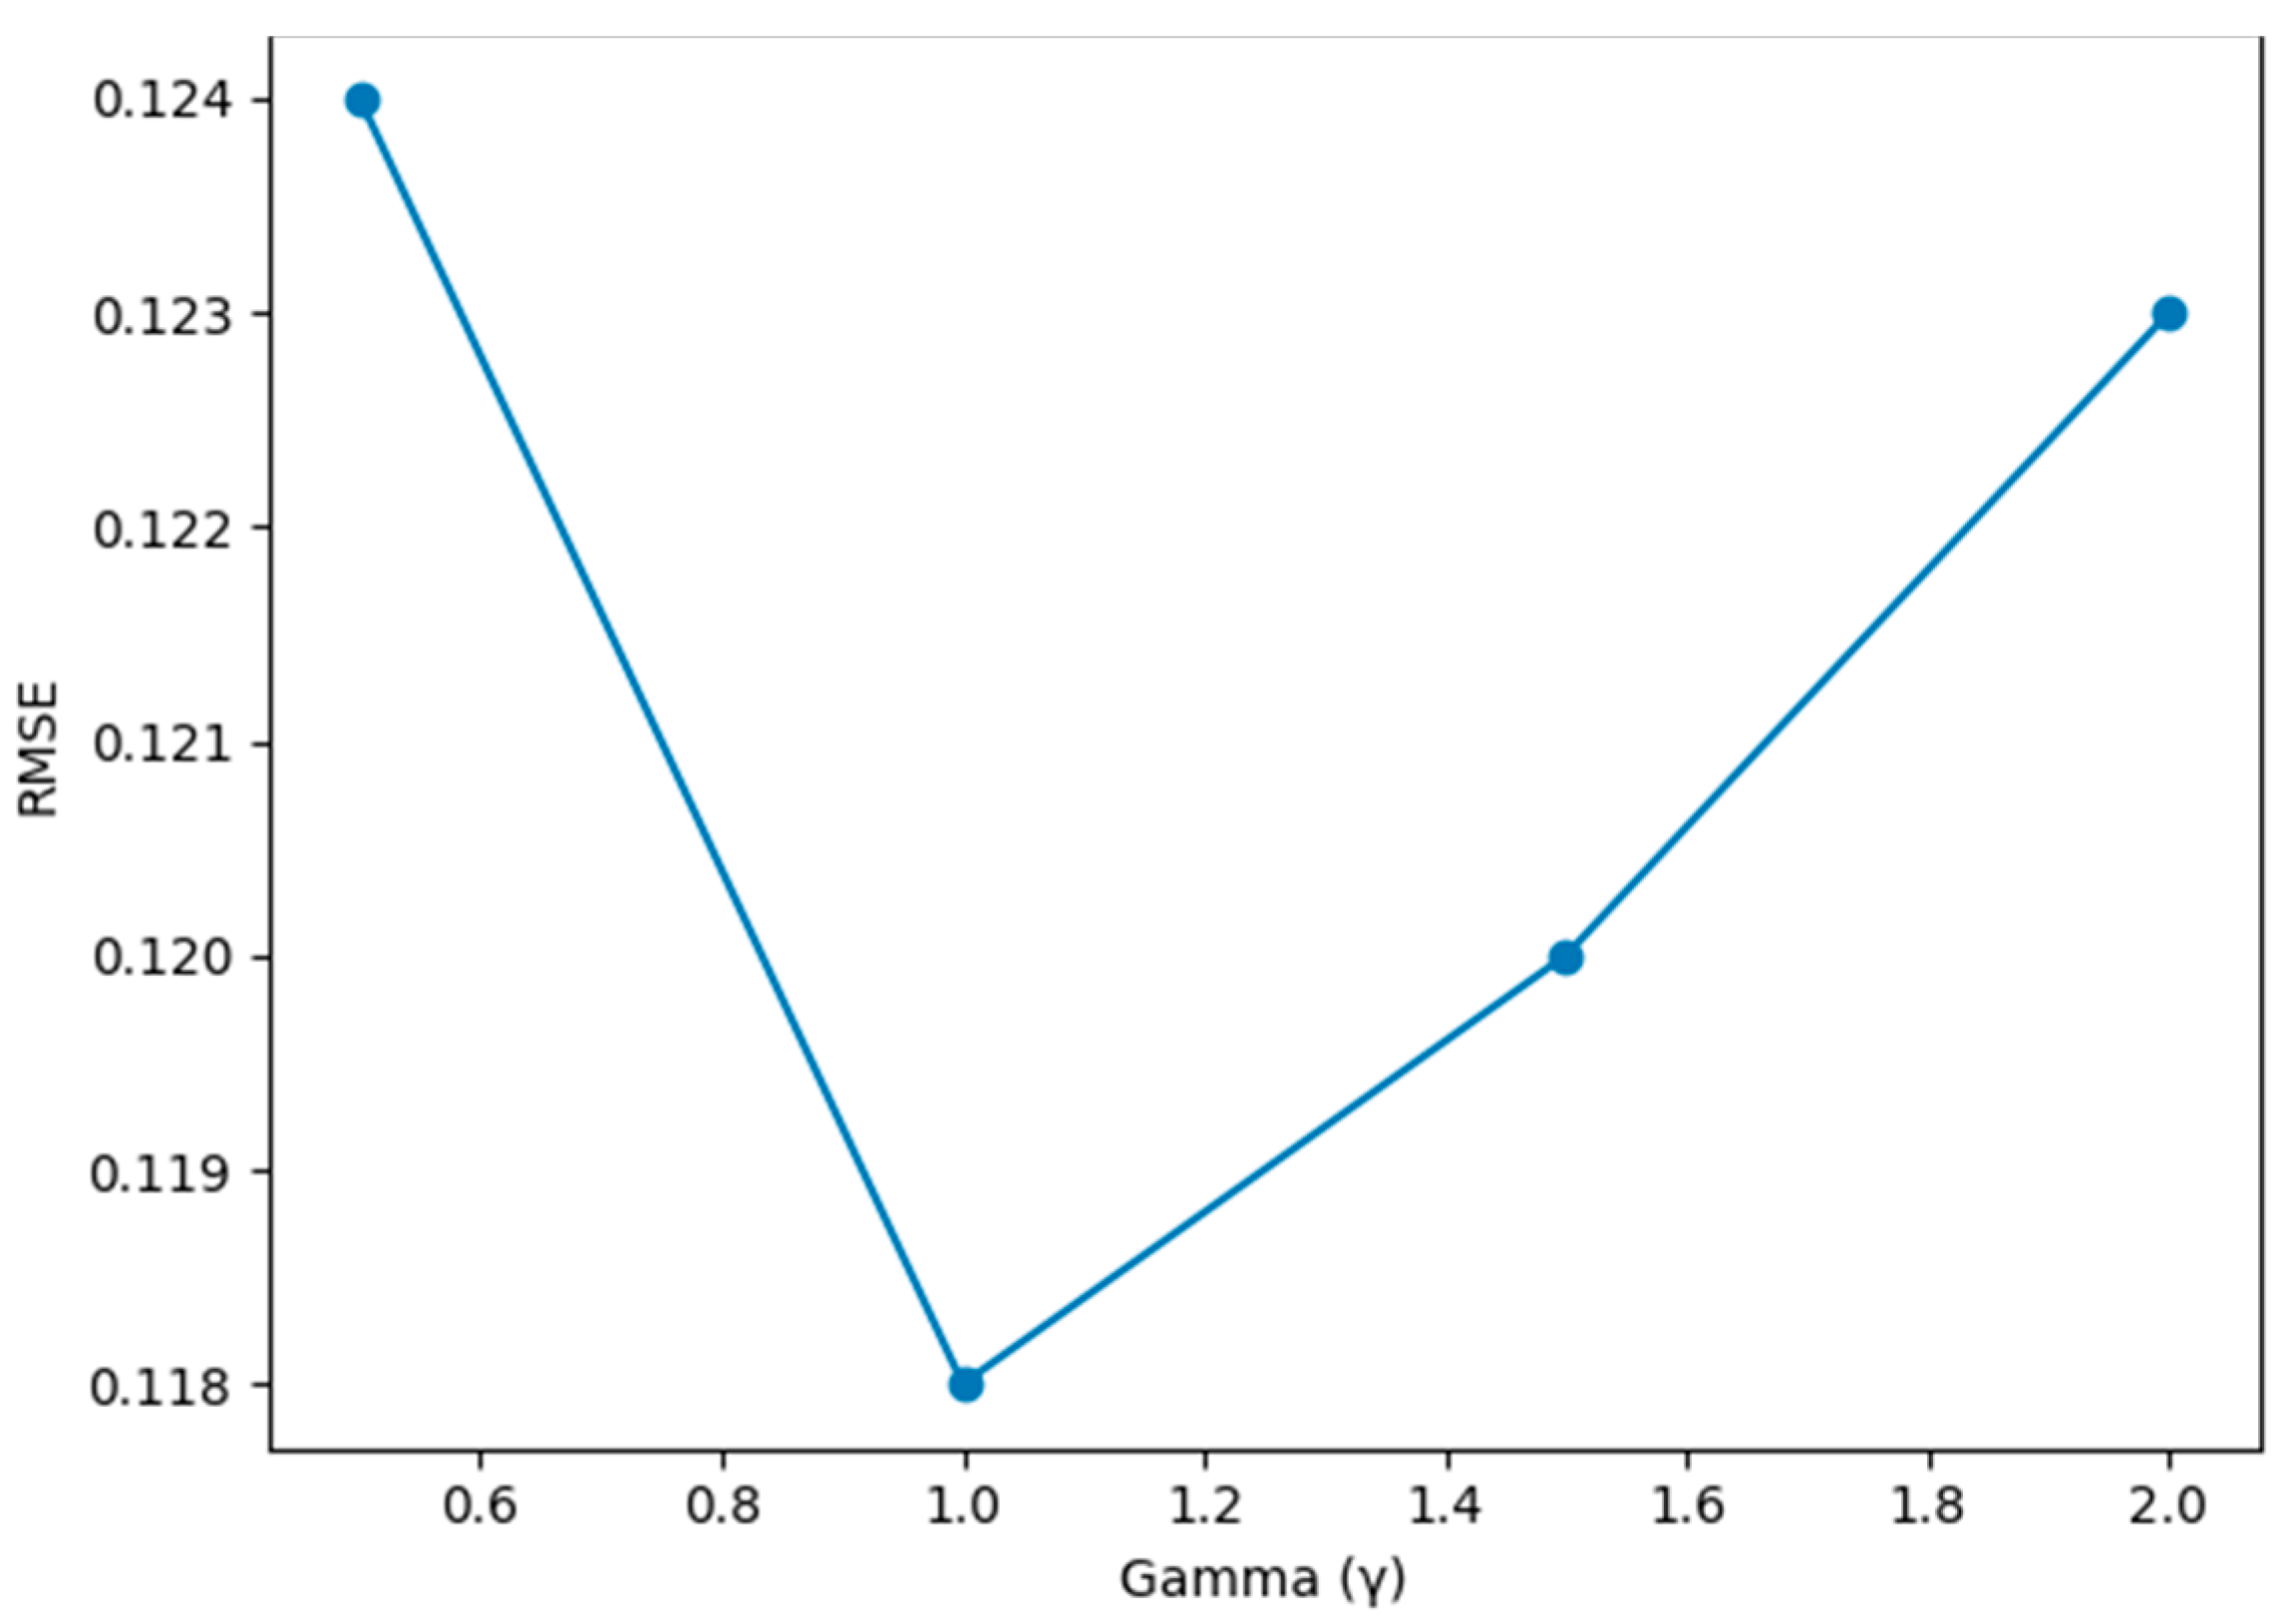

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.