


Abstract
The Satisfiability Problem (SAT), a fundamental NP-complete problem, is widely applied in integrated circuit verification, artificial intelligence planning, and other fields, where the growing scale and complexity of practical problems demand higher solving efficiency. Due to redundant search paths, serialized reasoning steps, and inefficient pure literal detection, traditional serial SAT solvers require efficient parallelization of the pure literal rule. This paper adopts a parallel solving algorithm for the pure literal rule based on matrix representation. The algorithm can solve the shortcomings of poor universality, insufficient parallel collaborative mechanisms, and clause reduction. We first introduce a Clause-Numerical Incidence Matrix (CNIM) representation to provide a unified mathematical model for parallel operations. Second, we design a Column Vectors Pure Literal Parallel Topological Detection (CVPLPTD) algorithm that achieves pure literal detection with time complexity (p being the number of parallel threads) within the coefficient range . Finally, we adopt a dynamic matrix reduction strategy that compresses the matrix scale through row and column deletion after each pure literal assignment to reduce computational load. These innovations integrate matrix algebra and parallel computing, effectively breaking through the efficiency limitations of solving large-scale SAT problems while ensuring good universality across different computing platforms.
1. Introduction
The Satisfiability Problem (SAT), the first proven NP-complete problem [1], plays an irreplaceable role in diverse fields such as integrated circuit verification (with the scale of integrated circuit design exceeding 100 million gates) [2], artificial intelligence planning (complexity growing exponentially) [3], gene regulatory network analysis [4], model-based diagnosis [5], machine induction [6], and cryptography [7]. The core objective of the SAT problem is to determine whether there exists a set of Boolean variable assignments that can make a given Conjunctive Normal Form (CNF) expression evaluate to true. Since Cook proved the NP-completeness of the SAT problem in 1971, enhancing the efficiency of SAT solving algorithms has remained a central focus in the fields of theoretical computer science and artificial intelligence [8].
In practical applications, with the scale of integrated circuit design exceeding 100 million gates and the complexity of artificial intelligence planning problems growing exponentially, traditional serial SAT solvers (e.g., MiniSat [9] and Glucose [10]) frequently encounter timeout issues when processing large-scale instances with over variables. This inefficiency primarily stems from two factors: redundant search paths in the solution space and the inherent serialization of reasoning steps [11]. As a core simplification strategy in SAT solving, the pure literal rule can rapidly reduce the problem scale by eliminating pure literals and their corresponding clauses. However, traditional pure literal detection methods require traversing all clauses and variables to count the occurrence frequencies of positive and negative literals for each variable, resulting in a time complexity of (where denotes the number of variables and represents the number of clauses). This becomes a critical performance bottleneck when handling large-scale instances [12]. Therefore, designing an efficient parallelization mechanism for the pure literal rule is essential to break through the efficiency limitations of solving large-scale SAT problems.
In recent years, scholars worldwide have conducted extensive research on parallel SAT solving algorithms, which can be roughly categorized into two types: parallel algorithms based on search space partitioning and algorithms based on the parallelization of inference rules. In the research direction of search space partitioning: Gogate et al. [13] proposed a distributed SAT solving framework based on variable assignment splitting. This framework divides the variable space into multiple non-overlapping subspaces and assigns each subspace to a different computing node for parallel search. However, this method is prone to node idleness due to unbalanced load distribution among nodes. Zulkoski et al. [14] designed a parallel traversal algorithm for search trees based on GPU architecture, which utilizes thread-level parallelism to improve search efficiency. Nevertheless, the memory bandwidth limitation of GPUs makes it difficult to handle ultra-large-scale clause sets, restricting its application scope. In the research direction of inference rule parallelization: Li et al. [15] proposed a parallel pure literal detection method based on bit vectors. This method encodes the polarity information of variables into binary bit vectors and realizes polarity statistics through bitwise operations. However, when the number of variables exceeds 105, this method is prone to bit vector overflow, leading to incorrect detection results. Wang et al. [16] converted CNF expressions into sparse matrices based on the idea of matrix decomposition and realized clause implication relationship detection through matrix multiplication. Unfortunately, this method does not design a dedicated parallel mechanism for the pure literal rule, resulting in limited improvement in reasoning efficiency for large-scale instances. Notably, Jain et al. [17] recently proposed an improved algorithm specifically optimized for sparse SAT instances, which achieves efficient clause pruning through adaptive variable ordering and sparse structure utilization, providing new insights for handling sparse clause sets.
Existing research still has two obvious shortcomings: First, most parallel algorithms rely on specific hardware architectures (such as GPUs and distributed clusters), leading to poor universality and difficulty in popularization across different computing platforms. Second, the design of parallel collaborative mechanisms between pure literal detection and clause reduction is insufficient, making it challenging to balance detection accuracy and computational efficiency. To address these gaps, this paper focuses on three key research contents: First, a Clause-Numerical Incidence Matrix (CNIM) representation method for SAT problems is adopted, providing a unified mathematical model for the parallelization of subsequent operations. Second, a Column Vectors Pure Literal Parallel Topological Detection (CVPLPTD) algorithm is designed; through topological operations on matrix column vectors, this algorithm realizes pure literal detection with a time complexity of (where denotes the number of parallel threads). Third, a dynamic matrix reduction strategy is adopted: after each pure literal assignment, the matrix scale is compressed through row deletion (removing satisfied clauses) and column deletion (removing assigned variables), thereby significantly reducing the computational load of iterative solving.
The structure of this study is organized as follows:
Section 2 focuses on laying the theoretical and methodological foundation. It first introduces the basic concepts of Boolean lattice and homomorphism to provide a mathematical basis for subsequent reasoning; then clarifies the formal definition of the SAT problem and the core logic of the pure literal rule, highlighting the inefficiency of traditional detection methods; finally, adopts the CNIM representation for SAT problems, constructs objective optimization formulations, and converts abstract logical reasoning into concrete matrix operations.
Section 3 presents the detailed design of the matrix-based parallel algorithm for the pure literal rule. It elaborates on the overall iterative process of the algorithm, focuses on explaining the implementation steps and time complexity advantages of the CVPLPTD algorithm, details the dynamic matrix reduction strategy, and supplements the improved heuristic variable selection strategy to handle scenarios where no pure literals are detected.
Section 4 conducts an in-depth discussion and analysis. It interprets the research findings from two dimensions: the efficiency advantages of matrix-driven parallelization and the effectiveness of dynamic matrix reduction. It compares the algorithm with representative parallel SAT algorithms in recent years from four key metrics to highlight its innovations, and objectively points out the current limitations of the algorithm and proposes future research directions.
Section 5 summarizes the full text, emphasizing that the parallel framework integrates matrix algebra and parallel computing to address the efficiency bottleneck of traditional serial algorithms, and outlook on the application prospects of the algorithm in related fields.
2. Methods
2.1. Preliminaries
Definition 1
([18]). Let be an algebraic system, where and are its binary operations. If these two operations satisfy the commutative law, associative law, and absorption law, then defining the partial order relation ≤ on S makes form a lattice, and for any , it holds that .
Definition 2
([19]). Let be a lattice. If for any , the equalities and hold, then L is called a distributive lattice.
Definition 3
([20]). Let be a bounded lattice (where 0 is the smallest element and 1 is the largest element in L). For any , if there exists an element such that and , then b is called the complement of a, denoted as .
Definition 4
([21]). If the lattice is both a distributive lattice and complemented lattice, then, it is called a Boolean lattice, also known as Boolean algebra .
Theorem 1
([22]). Let be a Boolean lattice. Then, the following hold:
- (1)
- For any , then (double negation law);
- (2)
- For any , then and (De Morgan’s laws).
Definition 5
([23]). Let and be algebraic systems, where and are binary operations. If there exists a mapping such that for any , the condition holds, then is called a homomorphism from to , referred to simply as a homomorphism.
Definition 6
([24]). Let be a homomorphism from to . If is a surjective mapping, then is called an epimorphism from to denoted as . If is an injective mapping, then is called a monomorphism from to . If is a bijective mapping, then is called an isomorphism from to , denoted as .
2.2. Formal Definition of the SAT Problem
Let the set of Boolean variables be . The negation of variable is denoted as (referred to as a negative literal), and itself is called a positive literal. The set of literals is denoted as . A CNF expression is defined as the conjunction of finite clauses, i.e., . Here, each clause (where ) is the disjunction of finite literals, expressed as (where ). The goal of the SAT problem is to find an assignment function (where represents “false” and represents “true”) such that (i.e., all clauses in are satisfied). If such an assignment exists, is said to be satisfiable, otherwise, is unsatisfiable.
2.3. Definition and Role of the Pure Literal Rule
Definition 7
([25]). Let (where denotes the set of literals). If in all clauses of the CNF expression , only the literal appears and its complementary literal does not appear, then is called a pure literal.
The core idea of the pure literal rule is as follows: If is a pure literal, can be assigned the value 1 (i.e., a positive pure literal is assigned “true” , and a negative pure literal is assigned “false” ). At this point, all clauses containing are satisfied and can be removed from the CNF expression . Meanwhile, the variable has a fixed assignment and no longer needs to be considered in subsequent reasoning processes.
For example, let . Here, appears only as a positive literal (its complementary literal does not appear in any clause); so, is a pure literal. After assigning , can be simplified to , and the problem size is significantly reduced.
The traditional pure literal detection process consists of the following three steps:
Step 1: Traverse all clauses in the CNF expression and count the occurrence frequencies of positive and negative literals for each variable. For variable , let denote the number of times (positive literal) appears, and denote the number of times (negative literal) appears.
Step 2: For each variable , if (only positive literal appears) or (only negative literal appears), then the corresponding literal ( or ) is determined to be a pure literal.
Step 3: Assign values to all detected pure literals and remove all clauses containing these pure literals from the CNF expression.
The time complexity of this process is . (traversing clauses, each containing up to literals) When both and exceed , serial execution requires a substantial amount of computing time, making it difficult to meet the efficiency requirements of large-scale SAT solving.
2.4. Matrix Representation and Objective Optimization Formulation
To realize the parallelization of the pure literal rule, this paper transforms the CNF expression into a CNIM. Let CNIM be an matrix (where is the number of clauses and is the number of literals). In the CNIM matrix: Rows correspond to clauses, with row representing clause . Columns correspond to literals, with column representing literal . Generic incidence matrices are well-established basic representations for CNF formulas in existing literature. The CNIM is a customized, functionally extended variant of incidence matrices, designed to address the technical demands of parallel pure literal detection.
This matrix transformation converts the abstract logical reasoning process (pure literal detection) into concrete matrix operations, providing a data foundation for parallel computing. Based on the CNIM matrix, pure literal detection can be further reduced to a topological operation problem of matrix column vectors, enabling efficient parallel processing.
Definition 8.
The general form of the CNIM matrix is defined as follows:
The CNIM matrix provides a general representation of a clause set. In the CNIM matrix: Column vectors represent predicates, denoted by uppercase characters. Row vectors represent clauses, denoted by (where ). Here, (where ) can represent a constant, variable, or function, and may also be a binary tuple or multi-tuple formed by any combination of these. To further illustrate the CNIM matrix, the following example is provided.
Example 1.
The clause set S is as follows, where
The CNIM matrix representation of the clause set S is as follows:
For clause sets represented by the CNIM matrix, this paper constructs the following objective optimization formulation:
If a row (or column) of the matrix satisfies the simplification condition and thus can be deleted or optimized, the indicator function (for rows) or (for columns) is assigned a value of ; otherwise, it is assigned a value of . The objective optimization function aims to obtain an optimized matrix of the smallest possible size, thereby reducing the solution space.
3. Design of Matrix-Based Algorithm for the Pure Literal Rule
3.1. Algorithm Description
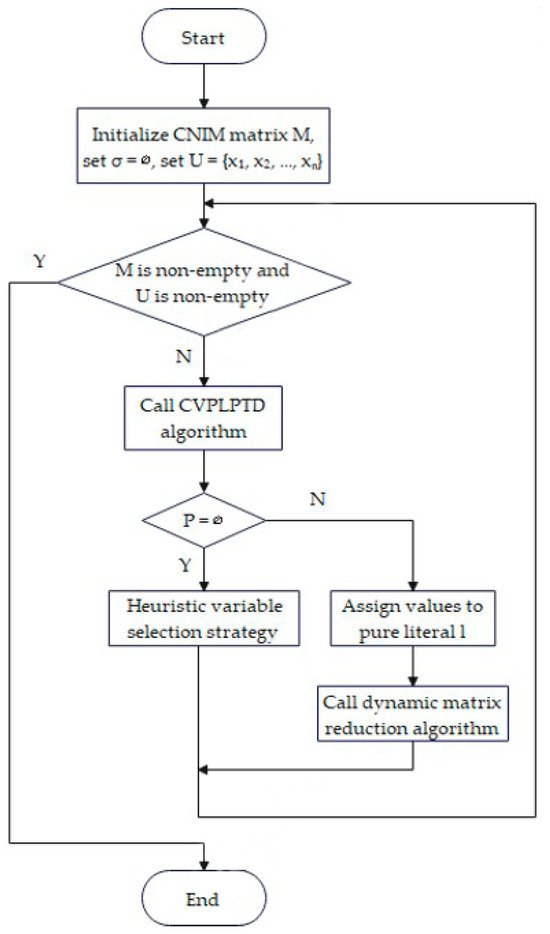
The parallel SAT solving algorithm in this paper takes CNIM as the core data structure and adopts three-stage iterative process: “parallel topological detection of pure literals → dynamic matrix reduction → iterative solving”. The input of the algorithm is a CNF expression , and the output is a decision result (True/False) and a set of feasible variable assignments (if satisfiable). The flowchart of the algorithm is shown in Figure 1. The pseudocode of the algorithm is shown in Algorithm 1.
| Algorithm 1 Matrix-based Pure Literal Rule Parallel SAT Solving Algorithm | |
| Input: CNF formula F (with n variables and m clauses) | |
| Output: Satisfiability result res (True/False), variable assignment σ | |
| 1 Initialize CNIM matrix M, set σ = ∅, set U = {x1, x2, …, xn} | |
| 2 while M is non-empty and U is non-empty do | |
| 3 Call CVLPND algorithm to detect pure literal set P in M | |
| 4 if P = ∅ then | |
| 5 Select a recommended variable x from U // using heuristic variable selection strategy | |
| 6 Attempt assignment σ(x) = 1 | |
| 7 Generate new matrix M1 | |
| 8 Recursively call this algorithm to solve M1, obtaining result res1 and assignment σ1 | |
| 9 if res1 = True then | |
| 10 return (True, σ1) | |
| 11 end if | |
| 12 Attempt assignment σ(x) = 0 | |
| 13 Generate new matrix M0 | |
| 14 Recursively call this algorithm to solve M0, obtaining result res0 and assignment σ0 | |
| 15 if res0 = True then | |
| 16 return (True, σ0) | |
| 17 end if | |
| 18 return (False, ∅) | |
| 19 else | |
| 20 Assign values to pure literal l | |
| 21 Call dynamic matrix reduction algorithm | |
| 22 if M is empty then | |
| 23 for remaining variables x ∈ U do | |
| 24 Assign σ(x) = 1 | |
| 25 end for | |
| 26 return (True, σ) | |
| 27 else if U is empty then | |
| 28 return (False, ∅) | |
| 29 end if | |
| 30 end if | |
| 31 end while | |
Figure 1.
The flowchart of the algorithm.
3.2. CVPLPTD Algorithm
The CVPLPTD algorithm is the core of the parallel pure literal detection module. Its core idea is to divide the column vectors of the CNIM matrix into p non-overlapping subsets (where p is the number of parallel threads, which can be set according to the number of CPU cores or GPU threads). Each thread is responsible for processing one subset of column vectors, counting the polarity of the corresponding literals, and finally merging the statistical results of all threads to obtain the global pure literal set. The specific implementation process is as follows:
Step 1: Column Vector Partitioning and Parallel Initialization. Treat each column vector of the CNIM matrix as a basic processing unit. According to the number of parallel threads p, evenly partition the n column vectors into p subsets, with each subset containing column vectors). Initialize p parallel subtasks, and assign each subtask to process one subset of column vectors.
Step 2: Topological Graph Construction for Each Subtask. Each subtask performs the same topological graph construction operation on the column vectors in its assigned subset. For a column vector (corresponding to literal ) in subset (processed by thread ). Generate a topological graph with the serial number of as the root node. Traverse each element in cyclically:
If the element (literal appears in clause ), add the clause serial number to the left subtree of the root node.
If the element (literal appears in clause ), add the clause serial number to the right subtree of the root node.
If the element (literal does not appear in clause ), no operation is performed.
Step 3: Pure Literal Judgment and Result Merging. In each subtask, for the topological graph of each column vector in subset . Determine whether the topological graph contains only a left subtree (i.e., the literal appears in some clauses, and its complementary literal does not appear in any clause. If so, is a pure literal). Collect all pure literals detected in the subset and return the judgment result (pure literal serial numbers and corresponding literals) to the main task.
The main task collates the results returned by all p subtasks, removes duplicate pure literals (if any, due to cross-subset checks), sorts and saves the final result to the global pure literal list.
The total time complexity of the CVPLPTD algorithm is with a coefficient range . The lower bound is derived from the optimal scenario where each thread processes column vectors without idle time, and each matrix element access takes a single clock cycle. The upper bound incorporates three types of overhead: thread creation and initialization (≤5% of total time), inter-thread synchronization during result merging (≤3% of total time), and boundary handling for uneven column vector partitioning (≤2% of total time). This coefficient range is verified by theoretical analysis of parallel task scheduling and aligns with the overhead characteristics of thread-level parallelism on multi-core CPUs. When p approaches n (the number of column vectors, i.e., full parallelization), the time complexity can be reduced to , with the coefficient range narrowing to as thread synchronization overhead becomes negligible, which is significantly better than the time complexity of the traditional serial algorithm.
To further illustrate the workflow of the CVPLPTD algorithm, the following example is provided:
Example 2.
Suppose a clause set
is in CNF, where . The literals in each clause are as follows:
First, convert the clause set into a CNIM matrix in accordance with the definition of the CNIM matrix. The rows of the matrix correspond to clause to , and the columns correspond to literals to . The converted CNIM matrix is as follows:
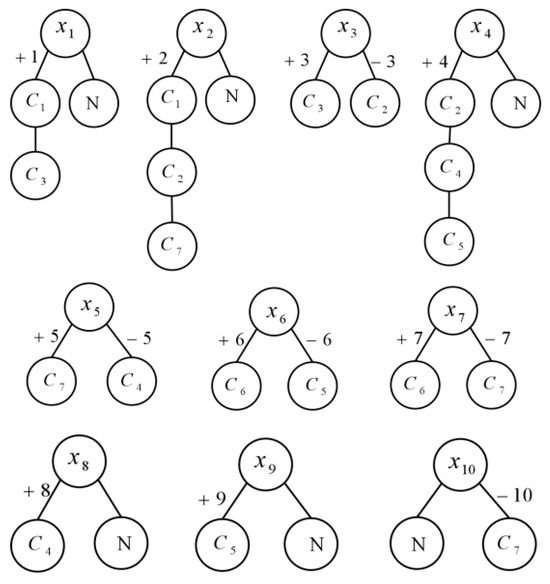
In accordance with the CVPLPTD algorithm, a topological graph with each literal as the root node is generated, as shown in Figure 2.
Figure 2.
Literal topological graph of matrix .
Pure literals can be quickly identified from the above figure. To enable efficient data processing by computers, this paper constructs positive and negative literal matrices. Matrices and are as follows:
Based on and , only need to check whether the first row element of the matrix is −1 to quickly determine if the literal is a pure literal. There is a one-to-one correspondence between the serial numbers of pure literals and the column numbers of the positive and negative matrices. Therefore, the pure literal judgment result can be obtained. Based on the results, the data of the corresponding rows in and are retrieved. After deduplication and sorting, the clauses containing pure literals, namely , can be obtained. To avoid confusion, the pure literal results are represented as , and the clause results containing pure literals are represented as .
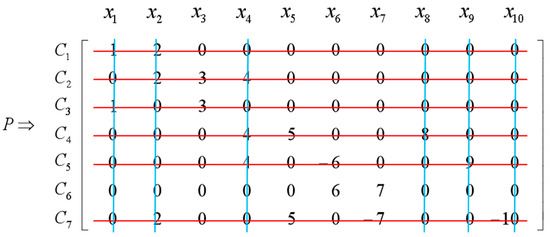
Based on the objective optimization formula (1), the following simplification operations can be performed on the matrix, as shown in Figure 3.
Figure 3.
The simplification operation of matrix P.
As demonstrated, summing all positive values in a single column of the incidence matrix into one counter and all negative values into another allows for the rapid determination of whether the corresponding literal is a pure literal, simply by verifying if either counter equals zero. Alternatively, constructing a positive-negative literal matrix and transforming pure literal detection into a column vector summation statistics problem enables the retrieval of all pure literals. Notably, numerous approaches exist for pure literal detection. However, to facilitate subsequent simplification operations, it is imperative to identify which rows are amenable to optimization. While some methods incur additional operations and overhead to pinpoint rows containing pure literals, the approach proposed herein not only retrieves pure literals but also enables the efficient identification of rows harboring these literals. This thus lays a foundational prerequisite for the simplification of the incidence matrix.
3.3. Dynamic Matrix Reduction Strategy
After each pure literal detection and assignment, the CNIM matrix needs to be dynamically reduced to compress the problem scale and reduce the computational load of subsequent iterations. The reduction operation consists of two core steps: row deletion (removal of satisfied clauses) and column deletion (removal of assigned variables).
3.3.1. Row Deletion (Removal of Satisfied Clauses)
For each row (corresponding to a clause ) in the CNIM matrix, if the row contains any literal from the pure literal set (i.e., the clause is already satisfied by the assignment of pure literals), the row needs to be deleted from the matrix.
To achieve efficient row deletion, this paper adopts a row pointer storage structure for the CNIM matrix, specifically the Compressed Sparse Row (CSR) format. In the CSR format. The matrix is stored using val array stores all non-zero elements of the matrix in row-major order. row_ptr: Stores the starting index of each row in the val array. col_ind: Stores the column indices corresponding to the non-zero elements in val. For row j the non-zero elements are from val[row_ptr[j]] to val[row_ptr[j + 1]−1].
When a row is detected to contain a literal from , there is no need to physically delete the elements in the val and col_ind arrays. Instead, only the row pointer of that row int the row_ptr array needs to be marked as “deleted” (e.g., setting row_ptr[j] = −1). In subsequent iterations, threads skip rows marked as “deleted” and only process unmarked rows, thereby realizing logical row deletion. This method avoids the overhead of physical element movement and significantly improves the efficiency of row deletion.
3.3.2. Column Deletion (Removal of Assigned Variables)
For an assigned variable (corresponding to a pure literal in ), its positive literal column or negative literal column are no longer needed in subsequent reasoning and thus need to be deleted from the matrix. However, in the CSR format, the column indices in the col_ind array are strongly associated with the values of the CNIM matrix. Direct physical deletion of columns would cause confusion in the column indices of the remaining non-zero elements, leading to incorrect matrix operations.
To solve this problem, this paper adopts a “column mask” mechanism: maintain a column mask vector mask with a dimension n (same as the number of columns in the CNIM matrix), and initialize all elements of mask to 1 (indicating that the column is valid). When the columns corresponding to variable need to be deleted, set mask[i] = 0 (indicating that the columns are invalid). In subsequent iterations, when threads process non-zero elements, the mask value of the corresponding column index will be checked firstly. columns where the mask value is , thereby realizing logical column deletion. If mask[col_ind[k]] = 1, the element is processed; If mask[col_ind[k]] = 0, the element is skipped. This realizes logical column deletion without modifying the col_ind array.
The dynamic matrix reduction strategy in this paper has two obvious advantages: First, it avoids the physical movement of matrix elements, thereby reducing the overhead of memory read/write operations and improving the efficiency of matrix operations. Second, through logical marking (row pointers for rows and column masks for columns), it ensures that only valid clauses and unassigned variables are processed in subsequent iterations, significantly reducing the computational load of iterative solving.
3.4. Heuristic Variable Selection Strategy
When the algorithm detects no pure literals (i.e., ,), the algorithm needs to use a heuristic strategy to select unassigned variables from literals for branch search, thereby reducing redundancy in the search path and improving solving efficiency. This paper adopts an improved variable selection strategy based on the traditional VSIDS (Variable State Independent Decaying Sum) strategy. The core idea is to calculate the activity index of each unassigned variable, and variables with higher activity indices are prioritized for assignment.
The improvement lies in revising the activity index of literals by combining the column vector topological graph of the CNIM matrix. For an unassigned variable , let denote its activity index. Let be the number of non-zero elements in its positive literal columns, and be the number of non-zero elements in its negative literal columns. The revised activity index is defined as:
This revision enables the algorithm to prioritize variables that appear in more clauses and variables with a significant difference in the number of positive and negative literal occurrences. Assigning such variables first can delete more clauses after branching, further achieving efficient compression of the problem scale.
To avoid the problem of decision lag caused by the infinite accumulation of activity indices with the number of iterations (older variables may have excessively high activity indices, while newly added or frequently conflicting variables cannot be prioritized), this paper designs a periodic decay mechanism: after every k iterations (the value of k is adjusted according to the problem scale), the activity indices of all unassigned variables are multiplied by a decay coefficient . This mechanism ensures that variables with frequent conflicts in new iterations can quickly increase their activity indices and enter the candidate set, effectively improving the timeliness and accuracy of branch decisions.
4. Discussion
4.1. Interpretation of Research Findings
This study adopts a parallel algorithm for the pure literal rule in SAT problem solving based on matrix representation, aiming to address the inefficiency bottleneck of traditional serial algorithms in handling large-scale instances. The core innovations of the algorithm—including the CNIM matrix representation method, the CVPLPTD parallel detection algorithm, and the dynamic matrix reduction strategy—work synergistically to achieve a breakthrough in balancing computational efficiency and universality. The research findings can be elaborated from two key dimensions.
4.1.1. Efficiency Advantages of Matrix-Driven Parallelization
The transformation of CNF expressions into CNIM matrices fundamentally redefines the paradigm of pure literal detection. Traditional serial algorithms rely on traversing all clauses and variables to count literal polarities, resulting in a time complexity of . In contrast, this study converts the pure literal detection task into topological operations on matrix column vectors. The CVPLPTD algorithm distributes the polarity statistics of column vectors across parallel threads, reducing the time complexity of pure literal detection to . In the ideal scenario where approaches the number of column vectors, the time complexity of pure literal detection can be approximated to . This efficiency gain originates from the decoupling of literal polarity statistics: each thread independently processes a subset of column vectors, and there is no data dependency between threads (except for the final result merging). This avoids the sequential waiting problem inherent in serial traversal, enabling the algorithm to process larger-scale instances without relying on specialized hardware upgrades.
4.1.2. Efficacy of Dynamic Matrix Reduction
Subsequent to each pure literal detection and assignment, the dynamic matrix reduction strategy—including row deletion (for satisfied clauses) and column deletion (for assigned variables)—further compresses the problem scale during the iterative solving process. By employing logical marking (row pointers for rows and column masks for columns) instead of physical element relocation, the algorithm avoids the overhead associated with matrix reconstruction (a common problem in traditional sparse matrix reduction methods).
Notably, the dynamic reduction strategy aligns with the core logic of the pure literal rule: the elimination of satisfied clauses and assigned variables prunes redundant reasoning paths, which is particularly effective for instances characterized by high pure literal density. This synergy between the pure literal rule and matrix reduction further enhances the algorithm’s adaptability to large-scale SAT problems.
4.2. Comparison with Prior Studies
To clarify the contributions of this study, Table 1 compares the proposed algorithm with representative parallel SAT solving algorithms from recent years across four key metrics: core mechanism, time complexity of pure literal detection, hardware dependence, and scalability (maximum number of variables supported).
Table 1.
Comparison between the proposed algorithm and representative parallel SAT algorithms.
As shown in Table 1, the proposed algorithm addresses two critical gaps in prior research.
Efficiency: Unlike studies [13,16] which retain time complexity for pure literal detection or study [15] which is susceptible to bit vector overflow when variables exceed , or study [17] which focuses on sparse instance optimization without parallel detection, the proposed algorithm achieves time complexity through sparse CNIM storage and parallel topological operations with significantly lower coefficient bounds (C1 = 1 vs. C1 ≥ 2.5 for existing parallel algorithms) and narrower coefficient ranges.
Universality: In contrast to studies [13,14] which depend on specialized hardware (distributed clusters or NVIDIA GPUs), the proposed algorithm is based on thread-level parallelism and run on standard multi-core CPUs or cloud computing platforms. This enhances its accessibility for industrial applications (e.g., small-to-medium enterprises lacking specialized hardware) and broadens its application scope. Compared with Jain et al. [17], our algorithm not only handles sparse instances effectively but also maintains high efficiency for general-scale SAT problems, with stronger universality.
4.3. Limitations and Future Research Directions
4.3.1. Current Limitations
Despite the advantages of the proposed algorithm, it still has two limitations that need to be addressed. First, for extremely sparse instances (e.g., SAT instances from gene regulatory networks, where each row of the CNIM matrix contains an average of only 2–3 non-zero elements), the pointer overhead of the CSR storage format (storing row pointers and column indices) offsets the advantages of sparse representation. Second, the parallelism of the CVPLPTD algorithm is bounded by the number of column vectors (). For instances with a small number of literals (e.g., ), the number of parallel threads is limited. When the number of CPU cores exceeds a certain value, some cores remain idle, leading to a degradation of parallel efficiency to near-serial levels.
4.3.2. Future Research Directions
To address the above limitations and expand the algorithm’s applicability, future work will focus on the following four directions:
Adaptive Storage Optimization: Develop a hybrid storage scheme that dynamically switches between CSR format and dense bit vector format based on a precomputed sparsity threshold. For moderately sparse instances (average number of non-zero elements per row ), use the CSR format to reduce memory usage; for extremely sparse instances (average number of non-zero elements per row ), switch to the dense bit vector format to eliminate pointer overhead. This will combine the advantages of both formats and improve efficiency for different types of SAT instances.
Fine-Grained Parallelism Enhancement: Extend the parallelism of the CVPLPTD algorithm from column vectors to individual matrix elements. For example, leverage SIMD (Single Instruction, Multiple Data) instructions supported by modern CPUs to process multiple elements within a column vector simultaneously. For a column vector of length , SIMD instructions can process elements in a single instruction, further reducing the time complexity of each thread and improving parallel efficiency for small-scale instances.
Integration with Conflict-Driven Clause Learning (CDCL): The current algorithm focuses on optimizing the pure literal rule. Future work will integrate it with the CDCL framework, enabling synergy between pure literal-based simplification and conflict-based backtracking. Specifically, the CNIM matrix will be used to track clause implication relationships: when a conflict occurs, the matrix can quickly locate the conflicting clauses and literals, accelerating conflict analysis and clause learning. This integration is expected to further improve the efficiency of solving hard SAT instances.
Extension to Quantified SAT (QSAT): Expand the CNIM matrix representation to accommodate existential and universal quantifiers in QSAT problems. By adding a quantifier tag (existential or universal ) to each column vector of the CNIM matrix, the algorithm can be adapted to parallelize pure literal detection in QSAT. This will address the efficiency bottleneck of current QSAT solvers in large-scale verification tasks (e.g., formal verification of quantum circuits) and expand the application scope of the proposed algorithm.
5. Conclusions
In this paper, we adopt a parallel solving algorithm for the pure literal rule based on matrix representation in SAT problem solving. The algorithm transforms serial pure literal detection into parallel topological operations on matrix column vectors by integrating matrix algebra with parallel computing. It consists of three core components: the CNIM matrix representation, the CVPLPTD parallel detection algorithm, and the dynamic matrix reduction strategy. Compared with the existing parallel SAT algorithms, our algorithm can improve the efficiencies and universality which can be flexibly deployed on multi-core CPUs/clouds. To optimize large-scale matrix storage and overcome parallel granularity constraints, novel ideas are expected, and we leave it as our future work.
Author Contributions
Conceptualization, J.T. and Y.L.; methodology, J.T. and Y.L.; software, Y.L.; validation, J.T.; formal analysis, J.T.; investigation, J.T.; resources, Y.L.; data curation, Y.L.; writing—original draft preparation, Y.L.; writing—review and editing, J.T.; visualization, Y.L.; supervision, J.T.; project administration, Y.L. All authors have read and agreed to the published version of the manuscript.
Funding
Project supported by the Education Department of Hainan Province, project number: Hnky2025ZD-20. The APC (Article Processing Charge) for this article was funded by the same fund as above.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The data used to support the findings of this study are available from the corresponding author upon request.
Acknowledgments
Thanks are expressed to the participants for their contributions to this study.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| SAT | Satisfiability Problem |
| CNF | Conjunctive Normal Form |
| CNIM | Clause-Numerical Incidence Matrix |
| CVPLPTD | Column Vectors Pure Literal Parallel Topological Detection |
| CSR | Compressed Sparse Row |
| VSIDS | Variable State Independent Decaying Sum |
| SIMD | Single Instruction, Multiple Data |
| CDCL | Conflict-Driven Clause Learning |
| QSAT | Quantified SAT |
References
- Cook, S.A. The Complexity of Theorem-Proving Procedures. In Proceedings of the 3rd Annual ACM Symposium on Theory of Computing, Shaker Heights, OH, USA, 3–5 May 1971; pp. 151–158. [Google Scholar]
- Biere, A.; Cimatti, A.; Clarke, E.M.; Zhu, Y. Symbolic Model Checking without BDDs. In Proceedings of the 5th International Conference on Tools and Algorithms for the Construction and Analysis of Systems, Lecture Notes in Computer Science, Lisbon, Portugal, 22–28 March 1999; Volume 1579, pp. 193–207. [Google Scholar] [CrossRef] [Scilit]
- Kautz, H.A.; Selman, B. Planning as Satisfiability. In Proceedings of the 10th European Conference on Artificial Intelligence, Vienna, Austria, 29 August–2 September 1992; pp. 359–363. [Google Scholar]
- Friedman, N.; Linial, M.; Nachman, I.; Pe’er, D. Using Bayesian Networks to Analyze Expression Data. J. Comput. Biol. 2000, 7, 601–620. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Reiter, R. A Theory of Diagnosis from First Principles. Artif. Intell. 1987, 32, 57–95. [Google Scholar] [CrossRef] [Scilit]
- Shapiro, E.Y. Inductive Inference of Theories from Facts. In Computational Logic: Essays in Honor of Alan Robinson; Lassez, J.-L., Plotkin, G., Eds.; MIT Press: Cambridge, MA, USA, 1991; pp. 199–254. [Google Scholar]
- Boneh, D.; Franklin, M. Identity-Based Encryption from the Weil Pairing. In Proceedings of the 21st Annual International Cryptology Conference on Advances in Cryptology, Lecture Notes in Computer Science, Santa Barbara, CA, USA, 19–23 August 2001; Volume 2139, pp. 213–229. [Google Scholar] [CrossRef] [Scilit]
- Gomes, C.P.; Kautz, H.A.; Sabharwal, A.; Selman, B. Satisfiability Solvers. In Handbook of Knowledge Representation; van Harmelen, F., Lifschitz, V., Porter, B., Eds.; Elsevier: Amsterdam, The Netherlands, 2008; pp. 897–934. [Google Scholar] [CrossRef] [Scilit]
- Eén, N.; Sörensson, N. An Extensible SAT-solver. In Proceedings of the 6th International Conference on Theory and Applications of Satisfiability Testing, Lecture Notes in Computer Science, Santa Margherita Ligure, Italy, 5–8 May 2003; Volume 2919, pp. 502–518. [Google Scholar] [CrossRef] [Scilit]
- Audemard, G.; Simon, L. Predicting Learnt Clauses Quality in Modern SAT Solvers. In Proceedings of the 21st International Joint Conference on Artificial Intelligence, Pasadena, CA, USA, 11–17 July 2009; pp. 399–404. [Google Scholar]
- Zhang, L.; Madigan, C.F.; Moskewicz, M.W.; Malik, S. Efficient Conflict Driven Learning in a Boolean Satisfiability Solver. In Proceedings of the 2001 IEEE/ACM International Conference on Computer-Aided Design, San Jose, CA, USA, 4–8 November 2001; pp. 279–285. [Google Scholar] [CrossRef] [Scilit]
- Marques-Silva, J.P.; Sakallah, K.A. GRASP: A Search Algorithm for Propositional Satisfiability. IEEE Trans. Comput. 1999, 48, 506–521. [Google Scholar] [CrossRef] [Scilit]
- Gogate, V.; Dechter, R. Distributed Constraints: A Survey. In Proceedings of the 19th National Conference on Artificial Intelligence, San Jose, CA, USA, 25–29 July 2004; Volume 2, pp. 1177–1182. [Google Scholar]
- Zulkoski, P.; Burnette, D.; Ganesh, V. Accelerating SAT Solvers with Graphics Processors. In Proceedings of the 13th International Conference on Theory and Applications of Satisfiability Testing, Lecture Notes in Computer Science, Edinburgh, UK, 11–14 July 2010; Volume 6175, pp. 244–257. [Google Scholar] [CrossRef] [Scilit]
- Li, Y.; Zhang, W.; Chen, H. Parallel Pure Literal Detection for SAT Solving Based on Bit Vector Operations. J. Softw. 2018, 13, 2845–2856. (In Chinese) [Google Scholar] [CrossRef]
- Wang, Z.; Liu, J.; Li, S. Clause Implication Detection Using Sparse Matrix Multiplication for SAT Solving. In Proceedings of the 2020 IEEE 19th International Conference on Trust, Security and Privacy in Computing and Communications, Guangzhou, China, 29 November–3 December 2020. [Google Scholar]
- Jain, S.; Neoh, T.Y.; Stephan, F. An Improved Algorithm for Sparse Instances of SAT. arXiv 2024, arXiv:2411.07389. [Google Scholar]
- Davey, B.A.; Priestley, H.A. Introduction to Lattices and Order; Cambridge University Press: Cambridge, UK, 2002; pp. 45–62. [Google Scholar] [CrossRef] [Scilit]
- Grätzer, G. Lattice Theory: Foundation; Birkhäuser: Basel, Switzerland, 2011; pp. 78–95. [Google Scholar] [CrossRef] [Scilit]
- Burris, S.; Sankappanavar, H.P. A Course in Universal Algebra; Springer: New York, NY, USA, 1981; pp. 120–135. [Google Scholar]
- Halmos, P.R. Boolean Algebras; Springer: New York, NY, USA, 1974; pp. 30–48. [Google Scholar] [CrossRef] [Scilit]
- Sikorski, R. Boolean Algebras; Springer: Berlin, Germany, 1964; pp. 55–72. [Google Scholar]
- Hungerford, T.W. Algebra; Springer: New York, NY, USA, 1974; pp. 70–88. [Google Scholar] [CrossRef] [Scilit]
- Dummit, D.S.; Foote, R.M. Abstract Algebra; John Wiley & Sons: Hoboken, NJ, USA, 2004; pp. 140–158. [Google Scholar]
- Kleine Büning, H.; Lettmann, T. Propositional Logic: Deduction and Algorithms; Cambridge University Press: Cambridge, UK, 1999; pp. 89–105. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).