


Highlights
What are the main findings?
- We propose Lite-BSSNet, a lightweight blueprint-guided visual state space network that reframes the decoding process into three stages: structural blueprint generation, cross-layer bridging, and structural repair. This approach effectively addresses the coexistence of multi-scale objects and the tendency of slender structures to break in remote sensing semantic segmentation.
- Extensive experiments demonstrate that this method achieves state-of-the-art performance, while ablation studies and qualitative visualizations validate the effectiveness and efficiency of this decoding paradigm.
What is the implication of the main finding?
- The results indicate that Lite-BSSNet has the potential to be applied to high-resolution remote sensing segmentation tasks in resource-constrained settings, as it improves accuracy without increasing the number of parameters while maintaining low computational cost.
- The proposed blueprint–bridge–repair design provides a generalizable decoder paradigm: structural priors, cross-layer alignment, and structure-repair refinement, which may be extended to broader Mamba-based architectures and other remote sensing conditions.
Abstract
Remote sensing image segmentation requires balancing global context and local detail across multi-scale objects. However, convolutional neural network (CNN)-based methods struggle to model long-range dependencies, while transformer-based approaches suffer from quadratic complexity and become inefficient for high-resolution remote sensing scenarios. In addition, the semantic gap between deep and shallow features can cause misalignment during cross-layer aggregation, and information loss in upsampling tends to break thin continuous structures, such as roads and roof edges, introducing pronounced structural noise. To address these issues, we propose lightweight Lite-BSSNet (Blueprint-Guided State Space Network). First, a Structural Blueprint Generator (SBG) converts high-level semantics into an edge-enhanced structural blueprint that provides a topological prior. Then, a Visual State Space Bridge (VSS-Bridge) aligns multi-level features and projects axially aggregated features into a linear-complexity visual state space, smoothing high-gradient edge signals for sequential scanning. Finally, a Structural Repair Block (SRB) enlarges the effective receptive field via dilated convolutions and uses spatial/channel gating to suppress upsampling artifacts and reconnect thin structures. Experiments on the ISPRS Vaihingen and Potsdam datasets show that Lite-BSSNet achieves the highest segmentation accuracy among the compared lightweight models, with mIoU of 83.9% and 86.7%, respectively, while requiring only 45.4 GFLOPs, thus achieving a favorable trade-off between accuracy and efficiency.
1. Introduction
Semantic segmentation is a fundamental task in remote sensing and has emerged as a key tool for extracting urban spatial structures [1]. With the continuous advancement of imaging technology, the spatial resolution of remote sensing images has steadily improved. Leveraging their high-resolution surface observation capabilities, these images have been widely applied in various domains, including urban planning [2], environmental monitoring [3], precision agriculture [4], and national defense and security [5]. High-resolution scenes typically contain objects with large-scale variations, complex boundaries, and frequent occlusions, which place higher demands on multi-scale representation, long-range dependency modeling, and the delineation of thin structures. Accurate remote sensing image segmentation essentially requires a delicate balance between global context and local detail across multi-scale objects.
In recent years, the rapid development of deep learning has led to the replacement of traditional semantic segmentation methods by deep-neural-network-based approaches due to their superior segmentation accuracy. FCN [6] was the first model to transform a classification network into a fully convolutional network, paving the way for large-scale applications of deep learning in pixel-level visual tasks. However, it still exhibits notable limitations in fine-grained segmentation and boundary delineation. To overcome these issues, U-Net [7] introduced a symmetric encoder–decoder architecture in which the encoder extracts image features via convolutional layers (downsampling) and the decoder progressively restores spatial dimensions through transposed convolutions (upsampling). Consequently, extensive research has been conducted based on the U-Net framework in the field of remote sensing [8,9,10]. Meanwhile, remote sensing images pose unique challenges such as significant variations in object scales, complex terrain boundaries, and frequent occlusions. Such dense spatial dependencies [11] present substantial challenges for networks based on convolutional neural networks (CNNs) and vision transformers (ViTs). Although prior studies have sought to mitigate these issues by expanding the receptive field through large-kernel convolutions [12,13,14] and by employing ViTs [15,16] to enhance global context modeling, CNN-based models still lag behind ViTs in performance. However, ViTs incur high computational cost due to quadratic complexity when processing high-resolution remote sensing imagery.
Recently, Mamba-based derivative models [17,18] have shown great promise in modeling long-range dependencies with near-linear complexity in visual tasks. Building upon this, researchers have successfully incorporated Mamba as a decoder within U-Net architectures [19,20,21,22], achieving remarkable results. However, most of them directly feed multi-scale cross-layer features into the SSM module without carefully reorganizing heterogeneous and noisy information. In remote sensing, shallow features preserve fine textures and edges but are often noisy. Deep features are semantically rich but lack spatial details. This mismatch creates a pronounced semantic gap. Simple concatenation or dense connections across layers easily introduce redundancy and amplify noise propagation, which limits the full potential of state space models.
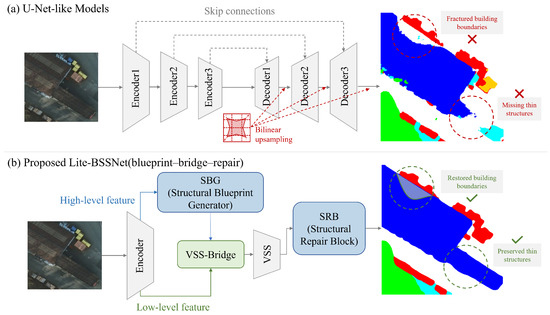
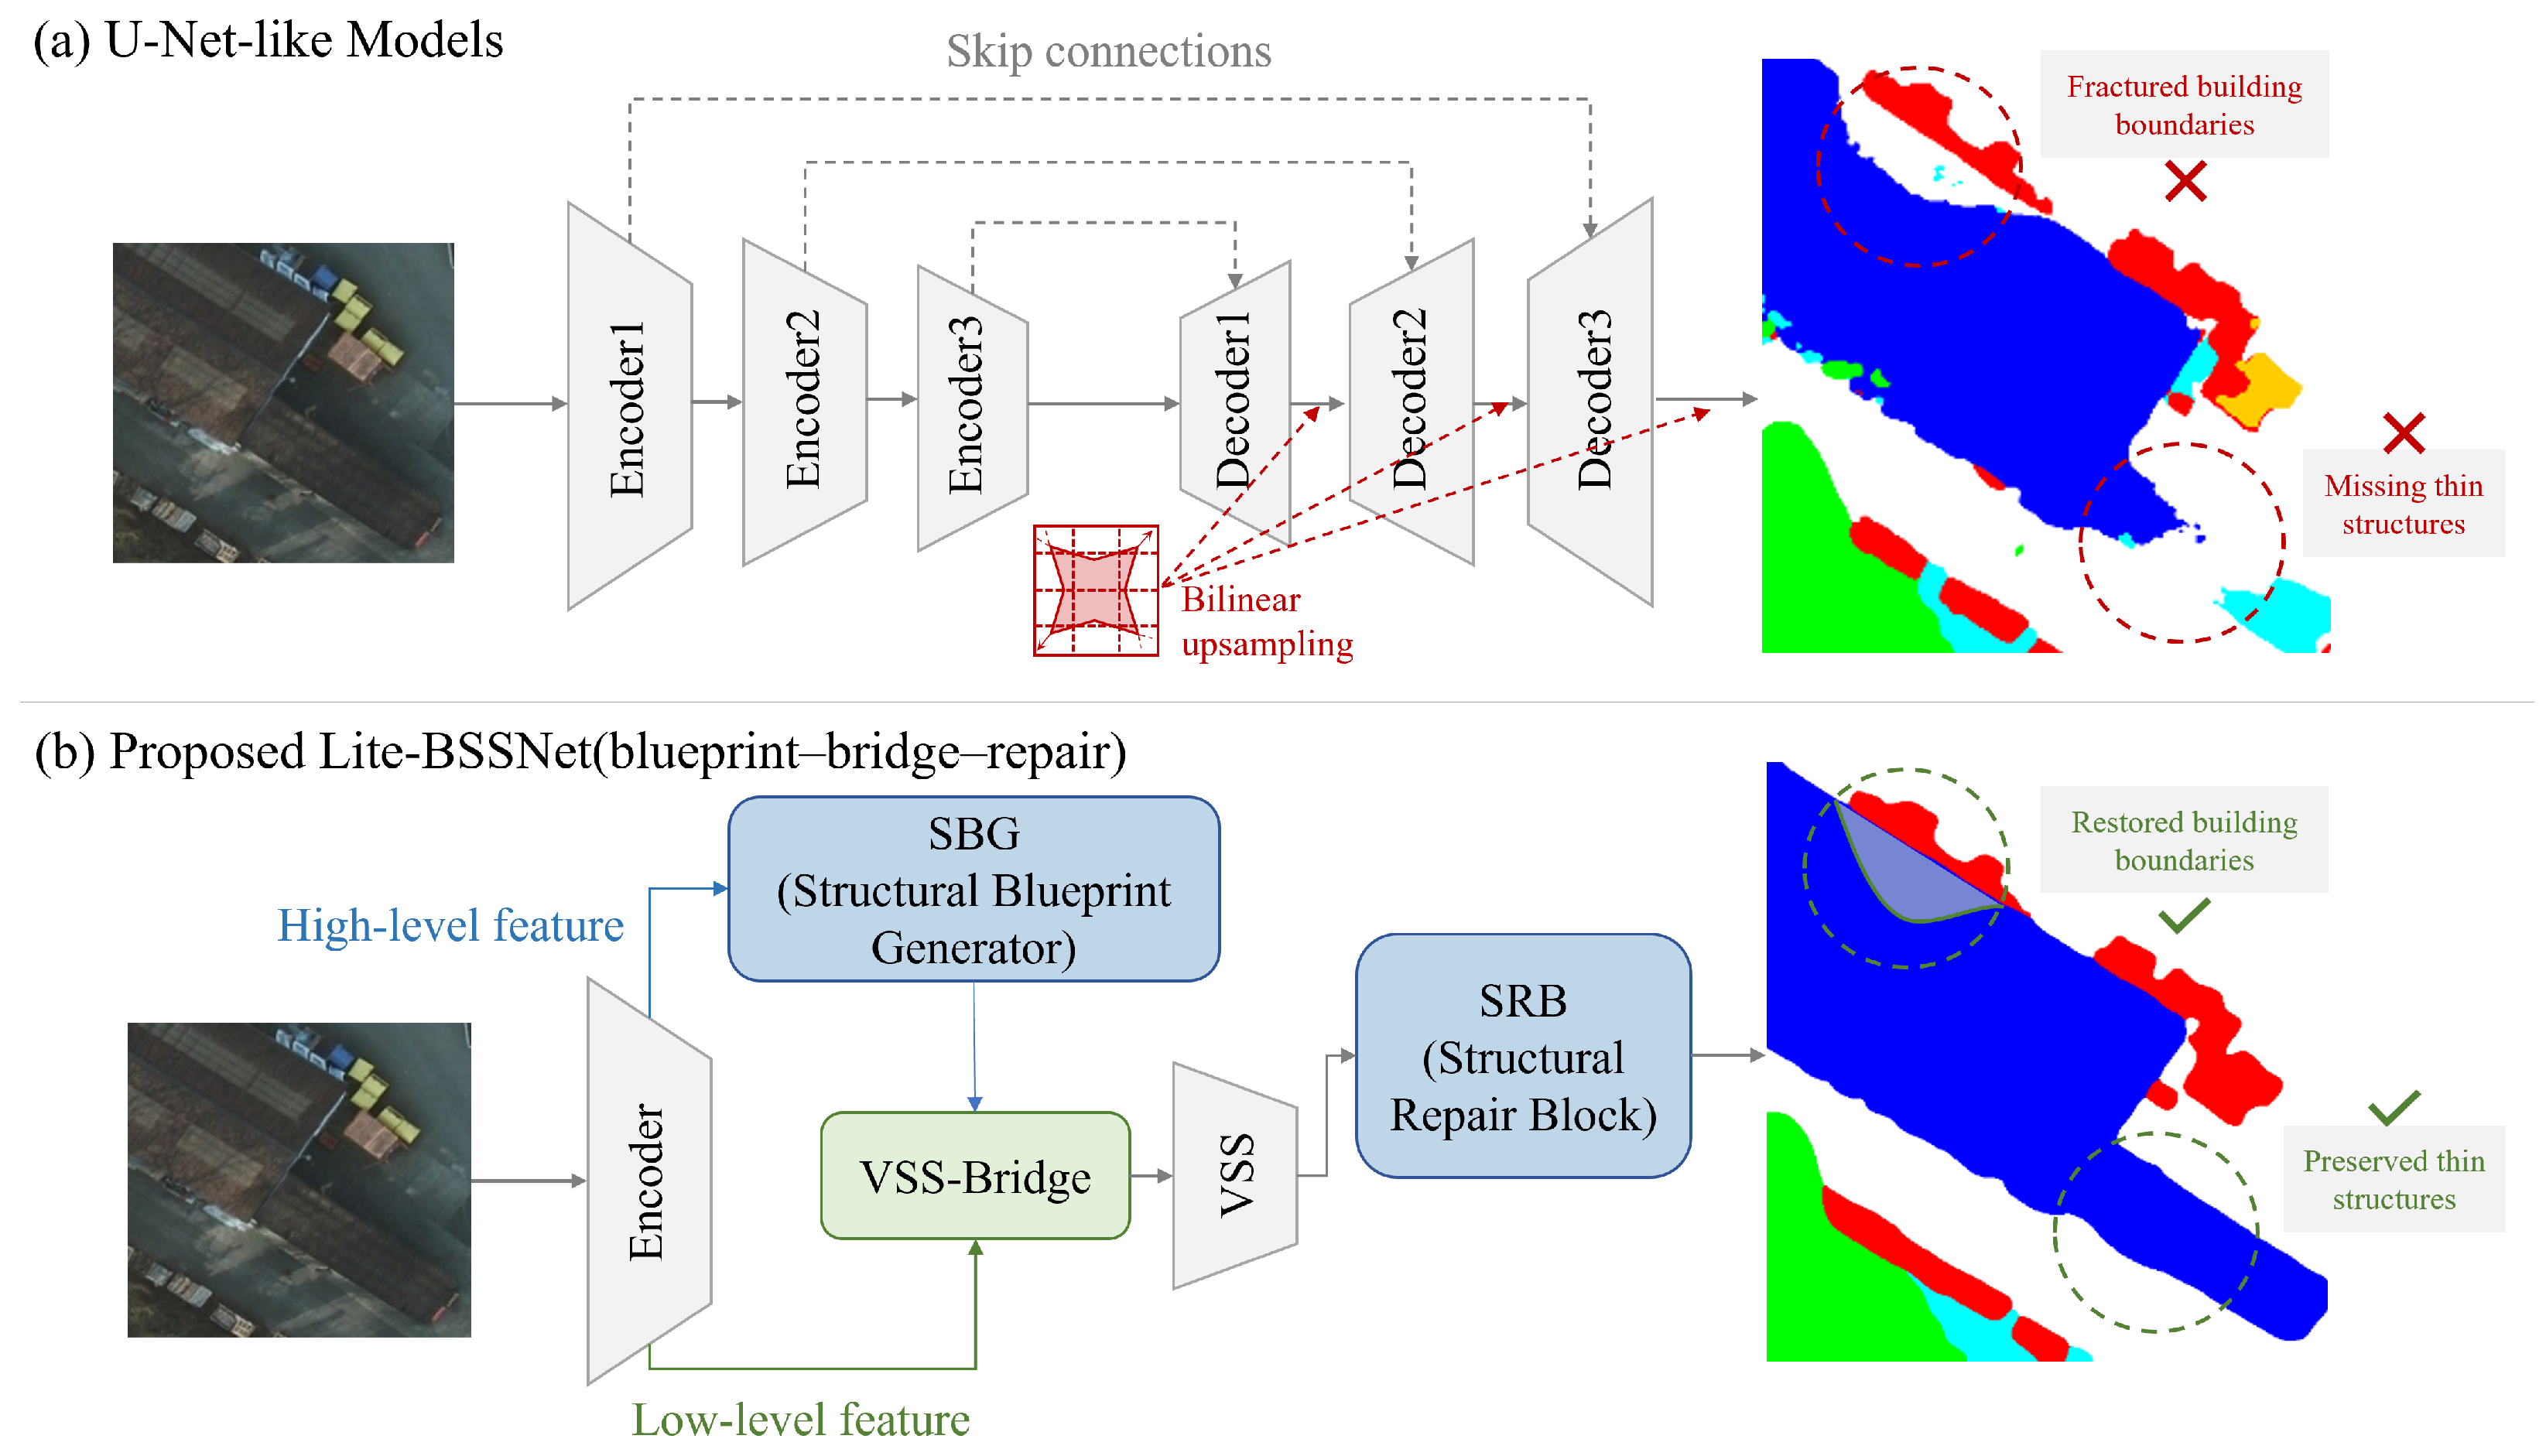
To alleviate cross-layer semantic misalignment, several studies have proposed dedicated cross-layer interaction modules. For example, CVMHUNet [23] introduces multi-frequency information via MFMSBlock and a pointwise convolution branch to refine local details, while Sparx [24] enhances feature reuse through sparse cross-layer connections. Although these methods improve cross-layer information utilization, they either incur considerable extra computation or ignore the impact of cross-layer design on the complexity of subsequent decoders and thus do not address the problem from a “complexity bridging” perspective. At the same time, interpolation-based upsampling in U-Net-like decoders often leads to broken thin structures such as roads and roof edges, as illustrated in Figure 1. Existing models rarely address this issue from a repair perspective. Instead, they typically add an extra refinement head at the end of the decoder. For example, UNetFormer [9] employs the FRH module and improves performance. However, the refinement branch is loosely coupled to the noise introduced during upsampling, which limits its repair capability.
Figure 1.
Motivation of the proposed Lite-BSSNet. (a) U-Net-like models with interpolation-based upsampling often produce fractured building boundaries and missing thin structures in high-resolution remote sensing scenes. (b) The proposed blueprint–bridge–repair decoding pipeline, consisting of the Structural Blueprint Generator (SBG), Visual State Space Bridge (VSS-Bridge), and Structural Repair Block (SRB), explicitly leverages structural priors and large-kernel refinement to restore building boundaries and preserve thin structures.
Structural priors and edge guidance are widely regarded as key cues for improving boundary quality and maintaining the continuity of fine structures in semantic segmentation. Classical methods incorporate contour constraints via active contours and energy minimization [25], or enforce spatial consistency using graphical models such as graph cuts [26]. In the deep learning era, edge-supervised mechanisms further strengthen boundary representations [27], and networks that explicitly model shape priors have demonstrated the importance of structural cues for accurate boundary localization and the preservation of thin, elongated objects [28]. However, remote sensing imagery is characterized by large-scale variations, cluttered textures, and frequent fragmentation of slender targets, making low-level edge responses prone to noise and instability. Motivated by these observations, we propose the SBG module to learn an edge-enhanced “structural blueprint” as a lightweight, learnable structural prior, providing stable structural constraints to guide the subsequent decoding process.
In this study, we revisit remote sensing semantic segmentation from a decoding perspective and propose Lite-BSSNet (Blueprint-guided State Space Network), a lightweight model. We adopt a pre-trained RegNet-Y [29] as the encoder to extract multi-scale semantic features with low computational cost and redesign the decoder as a three-stage pipeline: structural blueprint generation, state space bridging, and structural repair. Specifically, the Structural Blueprint Generator (SBG) transforms high-level semantic features into an edge-enhanced structural blueprint that acts as a topological prior to provide stable global structural constraints and guide cross-layer interactions. Building on this prior, the Visual State Space Bridge (VSS-Bridge) aligns and aggregates multi-level features to reduce semantic mismatch and redundancy and then uses axial interactions to project the fused features into a linear-complexity visual state space; this projection smooths strong edge gradients into scan-friendly representations, effectively connecting transformer-like spatial interactions to streaming state space modeling. Finally, the Structural Repair Block (SRB) combines small kernels with dilated convolutions to approximate a large receptive field and incorporates spatial and channel-wise gating, which suppresses upsampling-induced noise and repairs breaks in thin structures such as roads and roof boundaries, thereby improving topological consistency with negligible additional parameters and computation. The main contributions of this paper are summarized as follows:
- (1)
- We propose Lite-BSSNet, a blueprint-guided state space network that reformulates the decoding process of remote sensing semantic segmentation into three stages—structural blueprint generation, state space bridging, and structural repair—enabling efficient and robust segmentation in multi-scale, high-resolution scenarios.
- (2)
- We design a Structural Blueprint Generator (SBG) and a Visual State Space Bridge (VSS-Bridge). SBG produces an edge-enhanced structural blueprint as a topological prior, while VSS-Bridge aligns and aggregates multi-level features and projects axially interacted features into a linear-complexity visual state space, jointly bridging cross-layer semantics and computational complexity.
- (3)
- We propose a Structural Repair Block (SRB) that emulates a large receptive field through the combination of small and dilated convolutions and adopts spatial and channel-wise gating to suppress upsampling-induced noise and repair broken thin structures.
2. Related Work
2.1. CNN- and Transformer-Based Remote Sensing Image Segmentation Methods
With the advancement of deep learning technology, semantic segmentation techniques have found extensive applications in the field of remote sensing. Early research focused on CNNs, achieving efficient segmentation through local feature extraction. Among these, U-Net [7] significantly improved the accuracy of small-object segmentation by combining shallow high-resolution features with deep semantic representations, demonstrating outstanding performance in UAV-based building extraction [30,31] and high-resolution road segmentation [32]. This encoder–decoder framework subsequently became the standard architecture for remote sensing image segmentation networks [33,34,35]. Subsequent studies have refined this architecture through various improvements. For instance, Li [36] and Fu [37] introduced self-attention mechanisms to enhance the capability of capturing global contextual information. While CNN-based methods excel in extracting local details, their fixed receptive field size limits the model’s ability to represent global context effectively. The vision transformer (ViT) [15] directly models pixel-wise correlations across entire images using self-attention, establishing a new paradigm for large-scale segmentation in remote sensing. TransUNet [38] integrates Transformer modules into the U-Net framework, combining the global modeling power of ViTs with U-Net’s ability to preserve local details, thereby significantly improving segmentation performance. FTransUNet [39] further introduces an AdaMBA module to extract deep features and employs an inter-correlation mechanism to guide multimodal feature fusion, effectively capturing the complex spatial structures of remote sensing data. However, ViT’s global self-attention incurs high computational complexity, which limits its scalability to high-resolution and large-scale imagery. To address this, the Swin Transformer [40] proposes a “window self-attention + sliding window” mechanism that computes attention within local windows to reduce complexity while allowing cross-window information exchange through shifting operations. To satisfy the fine-grained requirements of remote sensing segmentation, ST-Unet [41] constructs a dual-encoder architecture that combines the Swin Transformer and CNN in parallel, integrating global dependencies into CNN features. Although transformer-based models provide superior global modeling capability, they remain computationally expensive, requiring significant hardware resources and posing challenges for deployment on low-power devices [42].
In this study, we designed a novel module by integrating the respective strengths of CNNs and Transformers, aiming to balance model efficiency and performance.
2.2. Mamba-Based Remote Sensing Image Segmentation Methods
To address the high computational cost of Transformers and the locality limitations of CNNs, the Mamba vision model based on state space models (SSMs) has been introduced into the field of remote sensing semantic segmentation [19,20,43]. Samba [44] is a semantic segmentation framework designed for high-resolution remote sensing imagery, which demonstrates the effectiveness of SSMs in this task. RS-Mamba [45] captures large-scale spatial features in remote sensing images through multidirectional global modeling using an omnidirectional selective scanning mechanism. Similarly, RS3Mamba [21] integrates Mamba into the U-Net architecture by constructing auxiliary branches based on the VSS module, providing additional global contextual information with near-linear computational complexity. UNetMamba [22] further proposes a pluggable Mamba-based segmentation decoder (MSD) for efficient semantic information decoding.
In this study, Lite-BSSNet explicitly restructures cross-layer information before state space decoding by generating an edge-enhanced structural blueprint and using a visual state space Bridge to filter, align, and project cross-layer features into the VSS domain.
2.3. Hybrid-Based Remote Sensing Image Segmentation Methods
Hybrid decoding architectures have recently become a research hotspot in remote sensing semantic segmentation. Their core concept is to utilize CNNs for efficient local feature extraction and Transformers or Mamba models for global feature modeling. Building upon this framework, different approaches emphasize different aspects. For example, STransFuse [8] employs dual branches to extract local and global features and fuses them adaptively through an attention mechanism. UNetFormer [9] introduces a global–local transformer block (GLTB) in the decoder stage, utilizing Transformer-based global modeling and CNN-based local feature extraction to enhance semantic associations and improve segmentation accuracy. UrbanSSF-S [20] integrates a feature state interaction mamba (FSI-Mamba) to model feature sequence relationships, combined with a global semantic enhancement (GSE) module and spatial interaction attention (SIA) mechanism to optimize feature representation. UMFormer [46] further reduces computational overhead through a lightweight attention mechanism and a Global–Local Visual State Space (GL-VSS) module.
In this study, Lite-BSSNet employs a blueprint-guided hybrid decoder: SBG generates edge-aware structural blueprints to suppress texture noise. Based on this blueprint, VSS-Bridge aligns cross-layer features and projects them into a state space representation for efficient long-range context aggregation; subsequently, SRB refines upsampled features via large receptive field convolutions and restores fine-grained structural connectivity.
3. Method
3.1. Overall
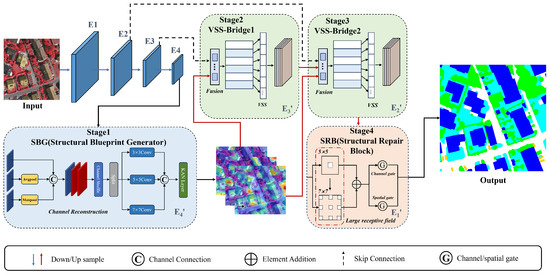
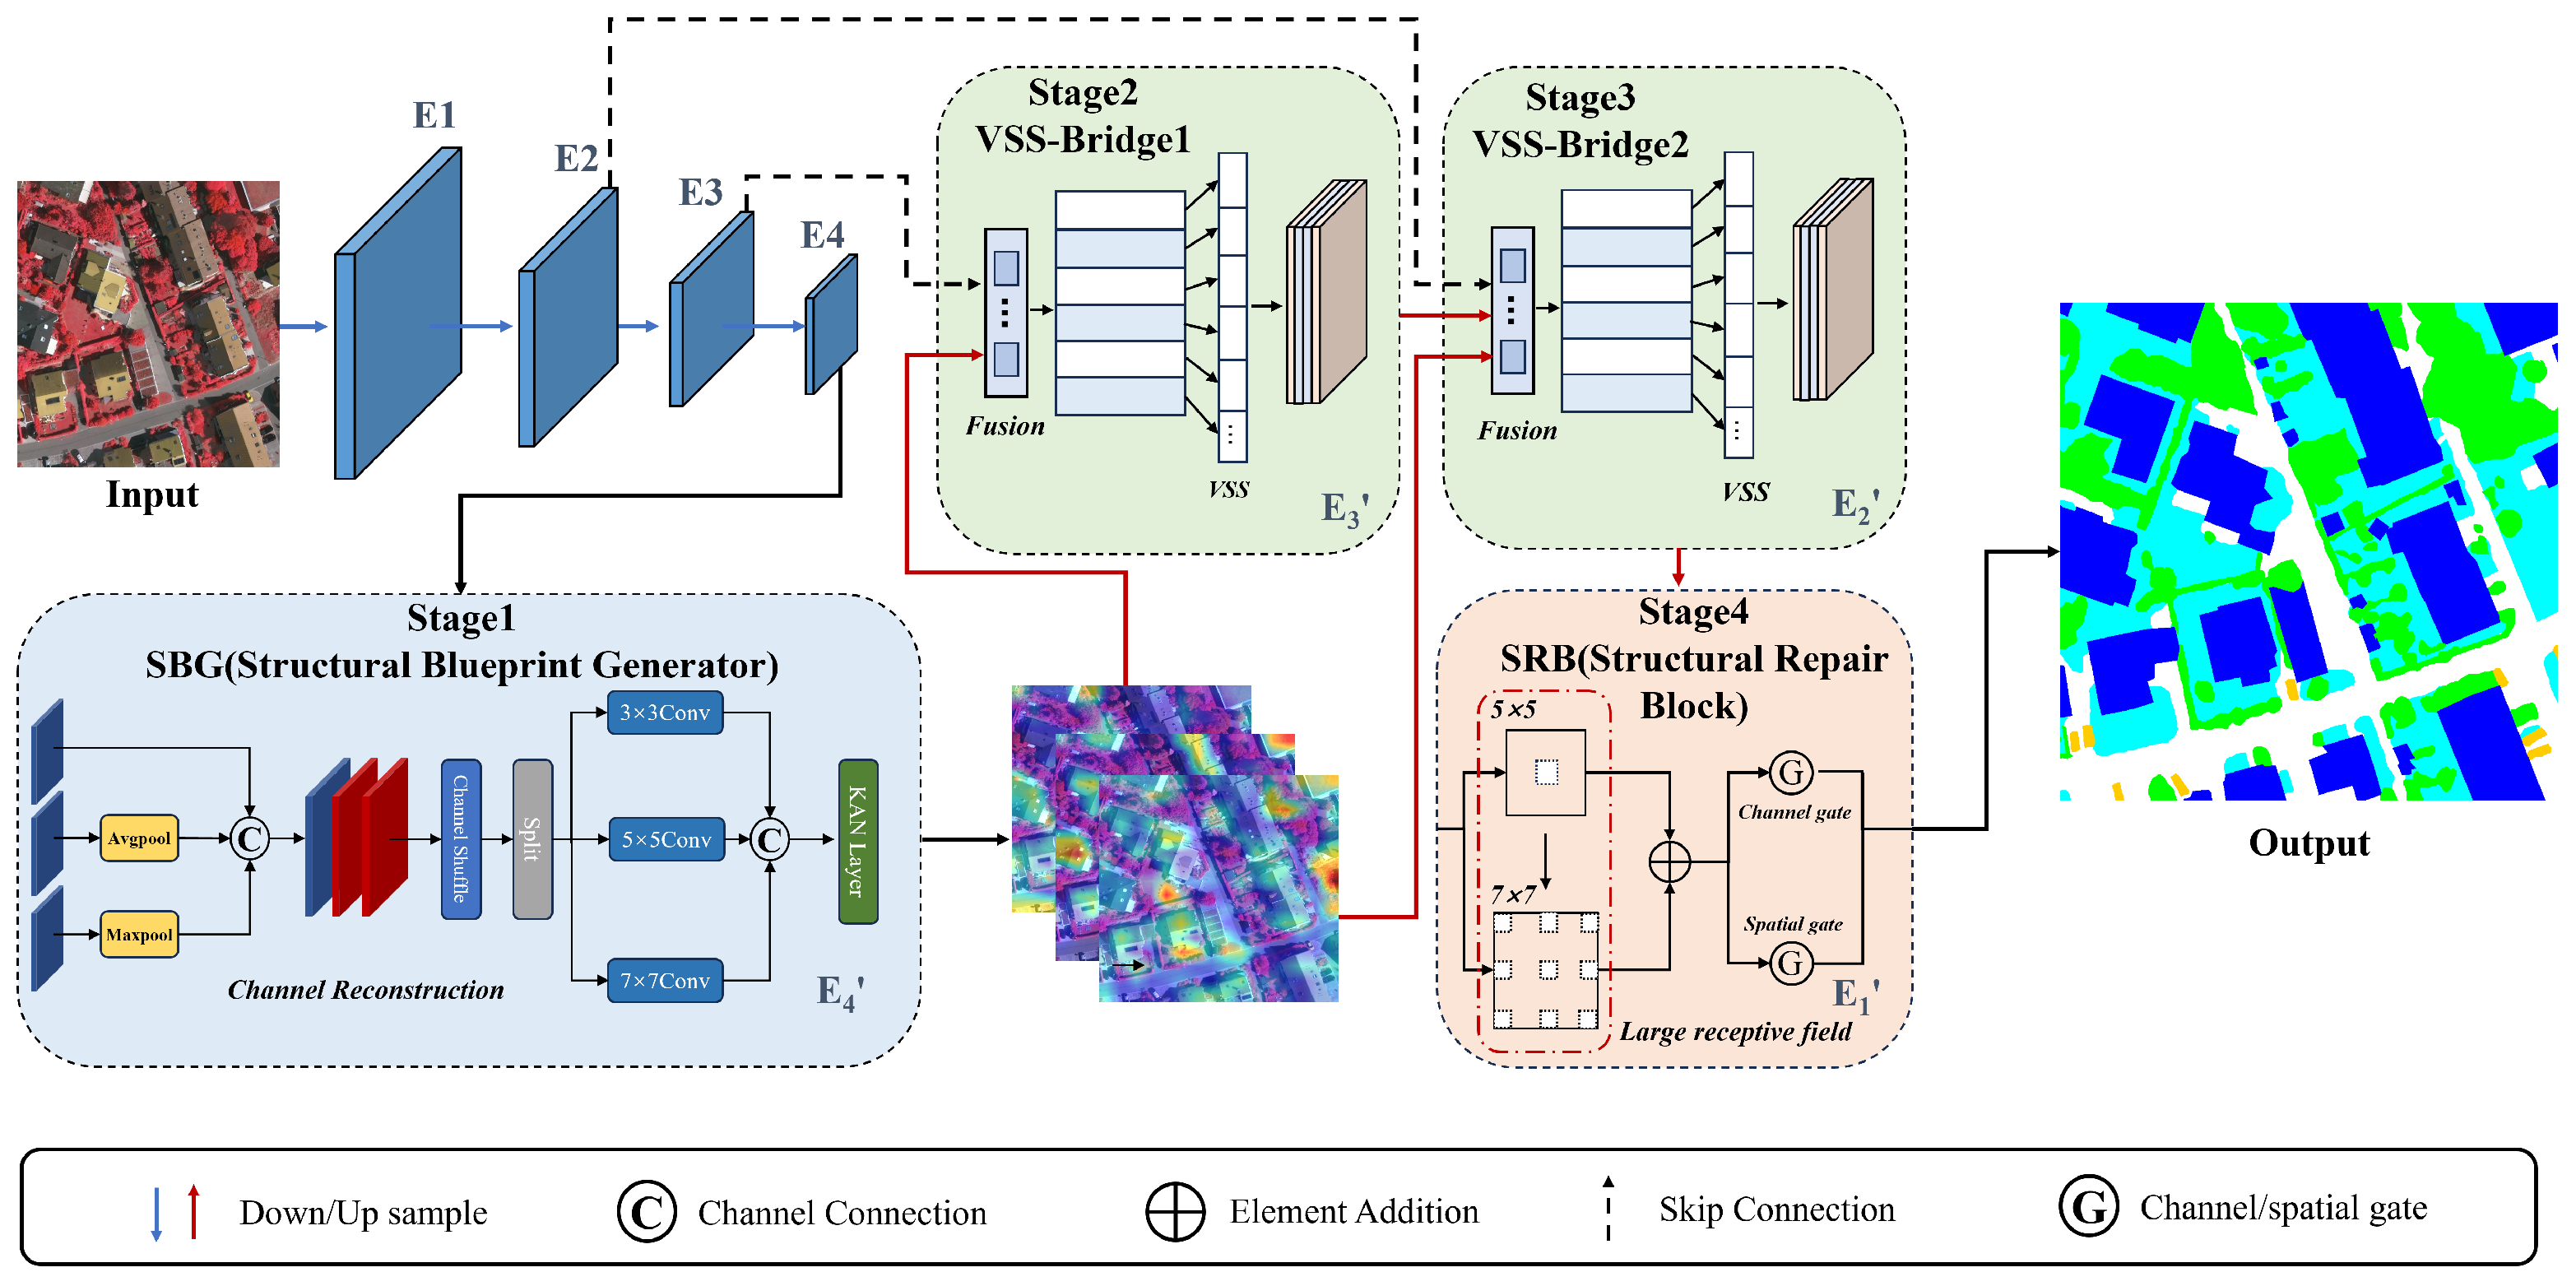
The overall architecture of the proposed Lite-BSSNet is illustrated in Figure 2. It follows an encoder–decoder framework. As RegNet has demonstrated a favorable balance between effectiveness and efficiency across a broad range of real-time semantic segmentation tasks, this study adopts a pre-trained RegNet-Y [29] as the encoder backbone. The encoder progressively extracts hierarchical feature maps, denoted as . On top of the deepest feature , a Structural Blueprint Generator (SBG) is applied to transform high-level semantics into an edge-enhanced structural blueprint, which serves as a topological prior to guide the subsequent decoding process.
Figure 2.
Architecture of our proposed Lite-BSSNet.
The decoder is built around a Visual State Space Bridge (VSS-Bridge) and a Structural Repair Block (SRB). The VSS-Bridge receives the structural blueprint together with selected cross-layer features and first encodes positional information via a dynamic position encoding (DPE) module [47]. DPE adopts a depthwise separable convolution (DWConv) [48], which is widely used in modern visual backbones, to dynamically inject spatial position cues into the feature maps. The position-aware features are then filtered and aligned across layers and fed into the Visual State Space (VSS) module from VMamba [18], which models long-range dependencies with near-linear complexity.
At the final decoding stage, the proposed SRB is employed to refine the high-resolution prediction. SRB combines several small convolution kernels with dilated convolutions to emulate the receptive field of a large convolutional kernel and further incorporates spatial and channel-wise gating. In this way, it suppresses noise accumulated during upsampling and explicitly repairs breaks in thin structures, enhancing topological consistency without incurring excessive computational cost.
Based on these components, Lite-BSSNet performs blueprint-guided cross-layer fusion in the early decoding stages through the VSS-Bridge, while the final stage focuses on structural refinement via SRB. The model is trained using the main loss function and an auxiliary loss function .
3.2. Structural Blueprint Generator (SBG)
To address the issues of low parameter efficiency and limited interpretability in conventional MLPs, Liu et al. [49] proposed Kolmogorov–Arnold Networks (KANs), which replace fixed linear weights with learnable activation functions on edges. This design provides strong interpretability and parameter efficiency and has recently demonstrated promising performance in semantic segmentation [50,51,52].
Compared with a conventional MLP, generating a boundary-oriented blueprint can be viewed as selective purification: it suppresses texture-like noise while enhancing class-transition cues and thin-structure continuity. KAN is well suited for this goal because it models cross-channel interactions with learnable univariate functions, enabling input-adaptive reweighting. This reweighting strengthens structure-consistent responses and suppresses spurious activations, producing a more stable structural prior. In contrast, convolutional alternatives mainly behave as local spatial filters and may blur or break thin structures.
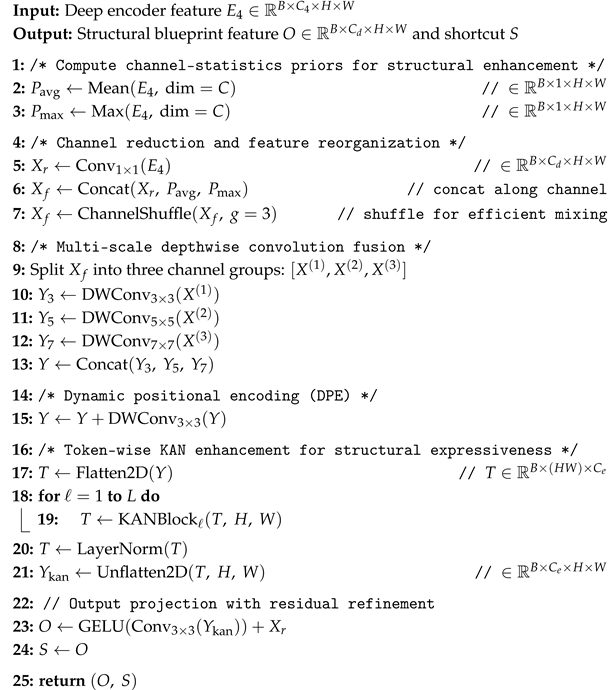
Meanwhile, features extracted from different encoder stages exhibit distinct characteristics: lower-level features capture fine-grained textures and boundary cues but are more susceptible to noise, whereas higher-level features are more semantic and category-specific, containing richer global structure. Motivated by this observation, we design a Structural Blueprint Generator (SBG) to enhance the deepest encoder feature and produce an edge-enhanced structural prior that facilitates subsequent structure-aware decoding. The overall process is shown in Algorithm 1.
| Algorithm 1: Structural Blueprint Generator (SBG) |
 |
- KAN formulation. Given an input token sequence , a K-layer KAN is constructed by composing multiple KAN layers:
Each layer maps an -dimensional input to an -dimensional output and is parameterized by a matrix of learnable univariate activation functions on edges:
The forward computation within layer k is defined element-wise as
where indexes tokens after flattening the 2D feature map and p and q index the input and output channels of the KAN layer, respectively. Each is a learnable univariate function defined on the edge .
3.3. Visual State Space Bridge (VSS-Bridge)
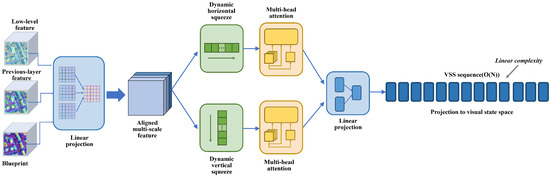
VMamba [18] models long-range dependencies with near-linear complexity and performs well on high-resolution remote sensing imagery. Motivated by this, we adopt the Visual State Space (VSS) module from VMamba as the sequential modeling component in our decoder. To support efficient VSS-based decoding, we introduce VSS-Bridge. It restructures heterogeneous cross-layer features and explicitly projects them into the VSS domain, as shown Figure 3.
Figure 3.
Architecture of the proposed Visual State Space Bridge (VSS-Bridge).
We implement the VSS-Bridge using a lightweight dynamic axial attention block with structural-guided gating. Specifically, denotes the current decoder feature, and denotes the collected cross-layer features. C, H, and W represent the channel number and the spatial height and width, respectively. In addition, we denote by b the structural blueprint generated by the SBG module. To explicitly inject structural priors into the decoder node, we first modulate using a gating mechanism derived from b:
where resizes the blueprint b to the spatial resolution . The convolution outputs C channels, so that can gate via element-wise multiplication, and ⊙ denotes the hadamard (element-wise) product.
We first concatenate the features in along the channel dimension. The concatenated features are then projected to channels through a linear layer and evenly split to form key and value candidates. In parallel, the current node feature is mapped to produce the query, key, and value features , , and :
where , denotes splitting the tensor along the specified dimension, and , , and denote linear projection functions for generating queries, keys, and values, respectively.
To reduce the computational and memory overhead associated with standard 2D self-attention, we employ a dynamic axial attention mechanism that performs interaction along one axis at a time. Specifically, we squeeze one spatial dimension via average pooling to obtain 1D axial tokens. For the row branch, we average over the width dimension:
where . Similarly, for the column branch, we average over the height dimension to obtain .
We then apply multi-head scaled dot-product attention (SDPA) to improve representation capacity. Let M be the number of attention heads and D the per-head dimensionality, such that . We reshape axial tokens into multi-head form:
To encode positional information in axial sequences, we introduce a learnable 1D positional embedding and interpolate it to the current length :
where P is a fixed-size learnable embedding and denotes linear interpolation.
The row-wise and column-wise attentions are computed as
where the in axial attention is applied along the axial sequence length (i.e., H for row-wise attention and W for column-wise attention). stabilizes the attention logits by the per-head dimensionality.
In the final fusion step, we broadcast the axial responses back to the 2D layout and introduce learnable mixing weights and to improve robustness:
where is broadcast from to by replication along the width dimension and is broadcast by replication along the height dimension. are learnable per-channel weights and are broadcast spatially.
The gated current-node feature and the attention-enhanced feature are concatenated along the channel dimension, followed by channel shuffling and a linear projection to obtain the aggregated output Y:
where denotes channel reordering and denotes feature concatenation.
Finally, to interface with the VSS module, we flatten the aggregated feature and reshape it back after VSS decoding:
where and follows raster order.
In this way, the bridge mitigates semantic gaps and redundancy across layers via axial cross-layer filtering. It also converts spatial interactions into a sequence-compatible representation for efficient visual state space decoding.
3.4. Structural Repair Block (SRB)
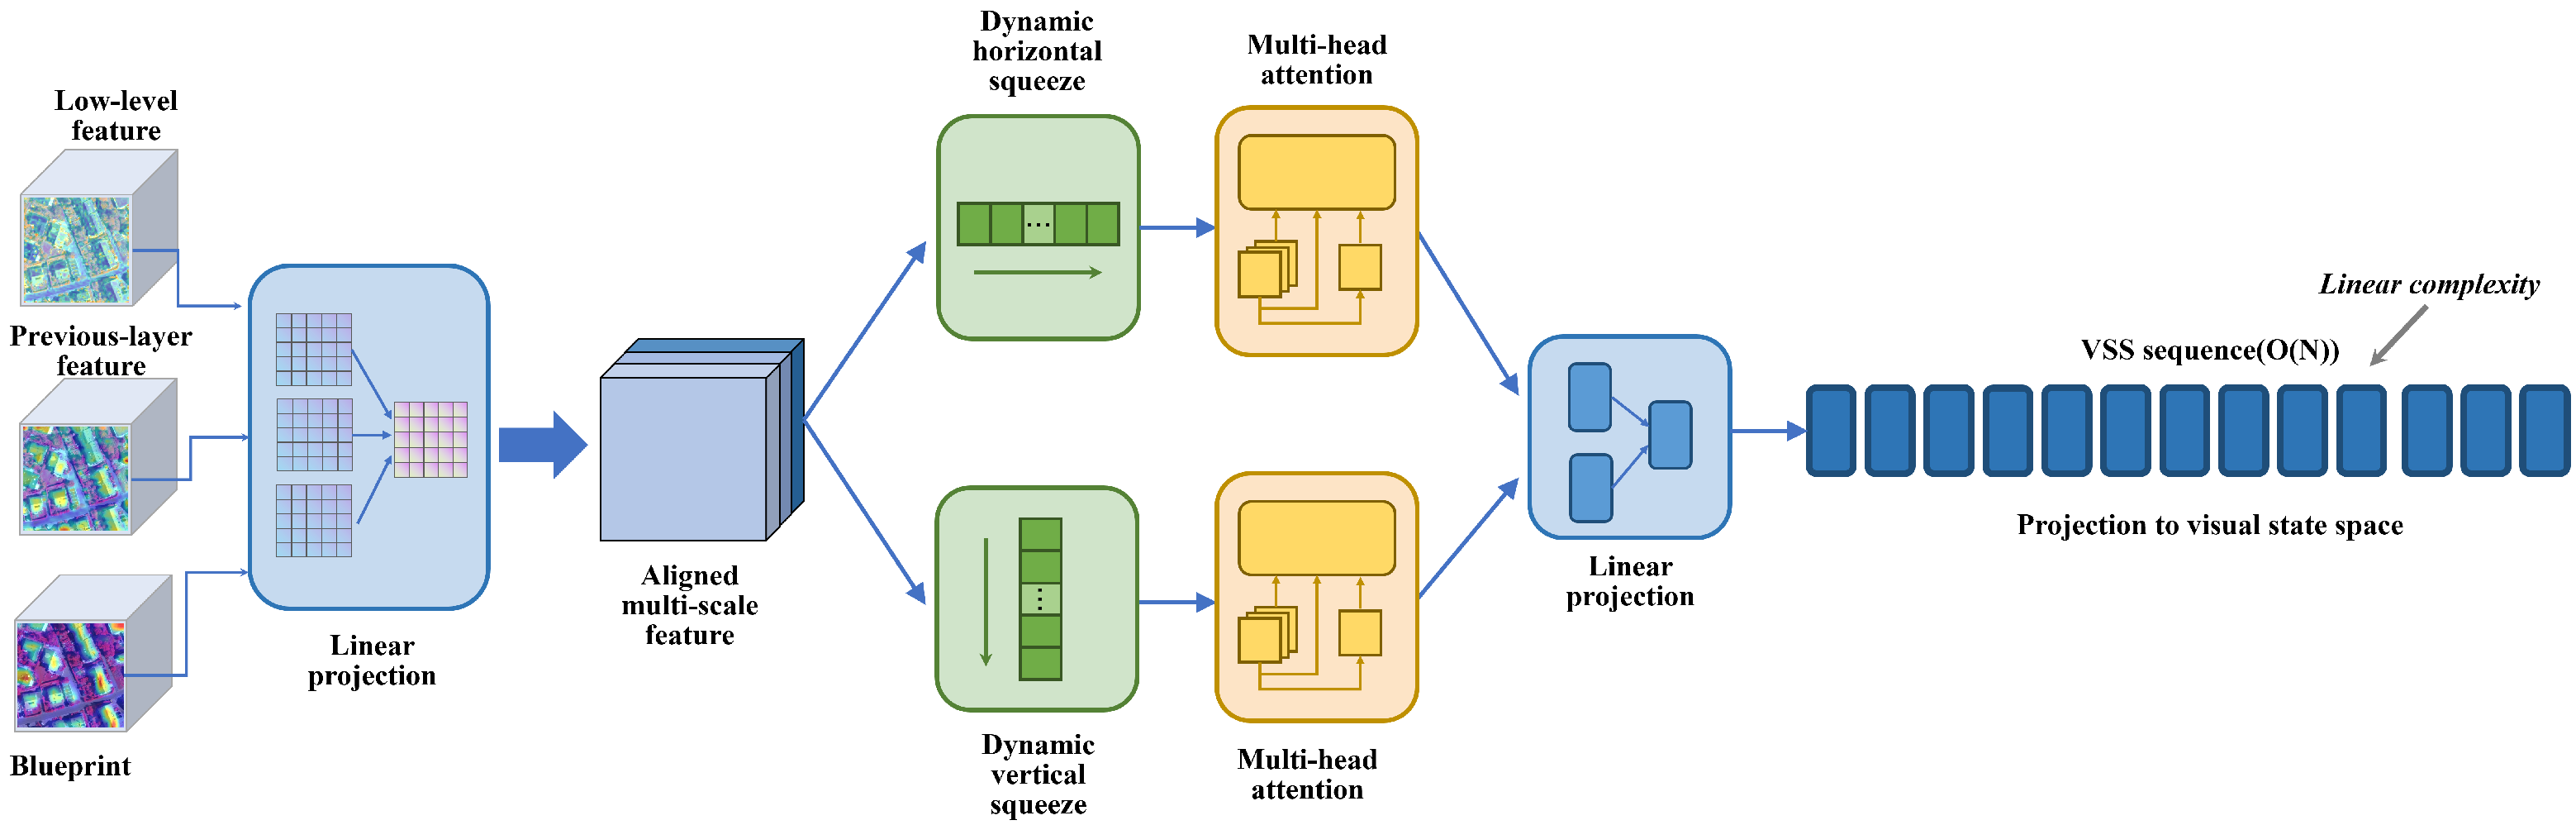
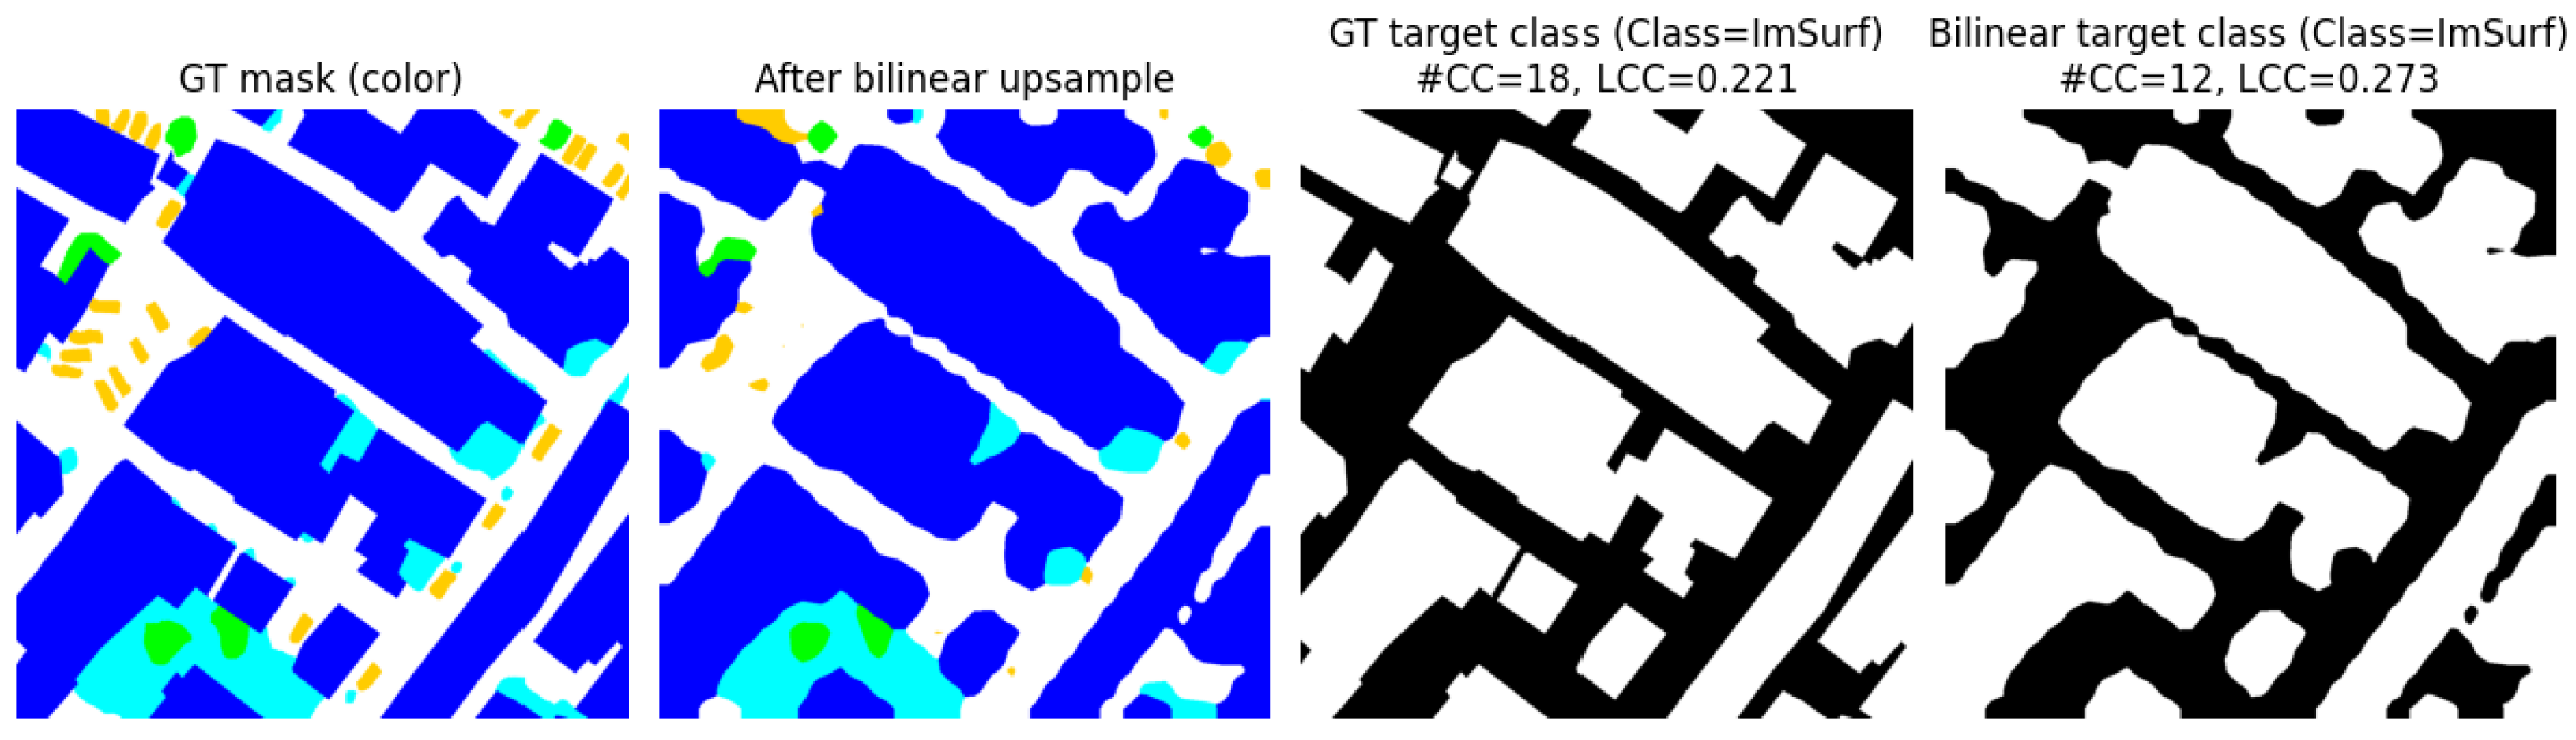
In the final stage of the decoder, deeper layers provide features enriched with multi-scale contextual information; however, repeated upsampling and multi-scale feature fusion may also accumulate noise and introduce structural distortions. Among these factors, interpolation-based upsampling is a key contributor. As a fixed-kernel resampling operation, interpolation smooths sharp contours and attenuates boundary responses of fine structures. As shown in Figure 4, bilinear resampling reduces the number of connected components while increasing the dominance of the largest connected component, indicating a tendency to merge fragmented regions and suppress minute or marginal structures. This behavior broadens the low-confidence transition band near object boundaries and may alter the topology of fine-grained regions. In practical decoders, boundary ambiguity and potential sub-pixel inconsistencies introduced by successive resampling and fusion can be further amplified by subsequent convolutional operations, leading to unstable boundary predictions.
Figure 4.
Effect of bilinear upsampling on structural connectivity.
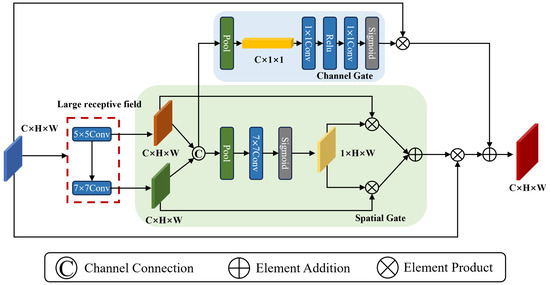
To address this issue, we design a lightweight Structural Repair Block (SRB). Large-kernel attention expands the receptive field and provides sufficient structural context for boundary decisions while preserving geometric continuity. Spatial and channel gating suppress unreliable boundary responses and selectively enhance geometrically coherent regions. As a result, SRB mitigates topology drift caused by over-smoothing and boundary blurring.
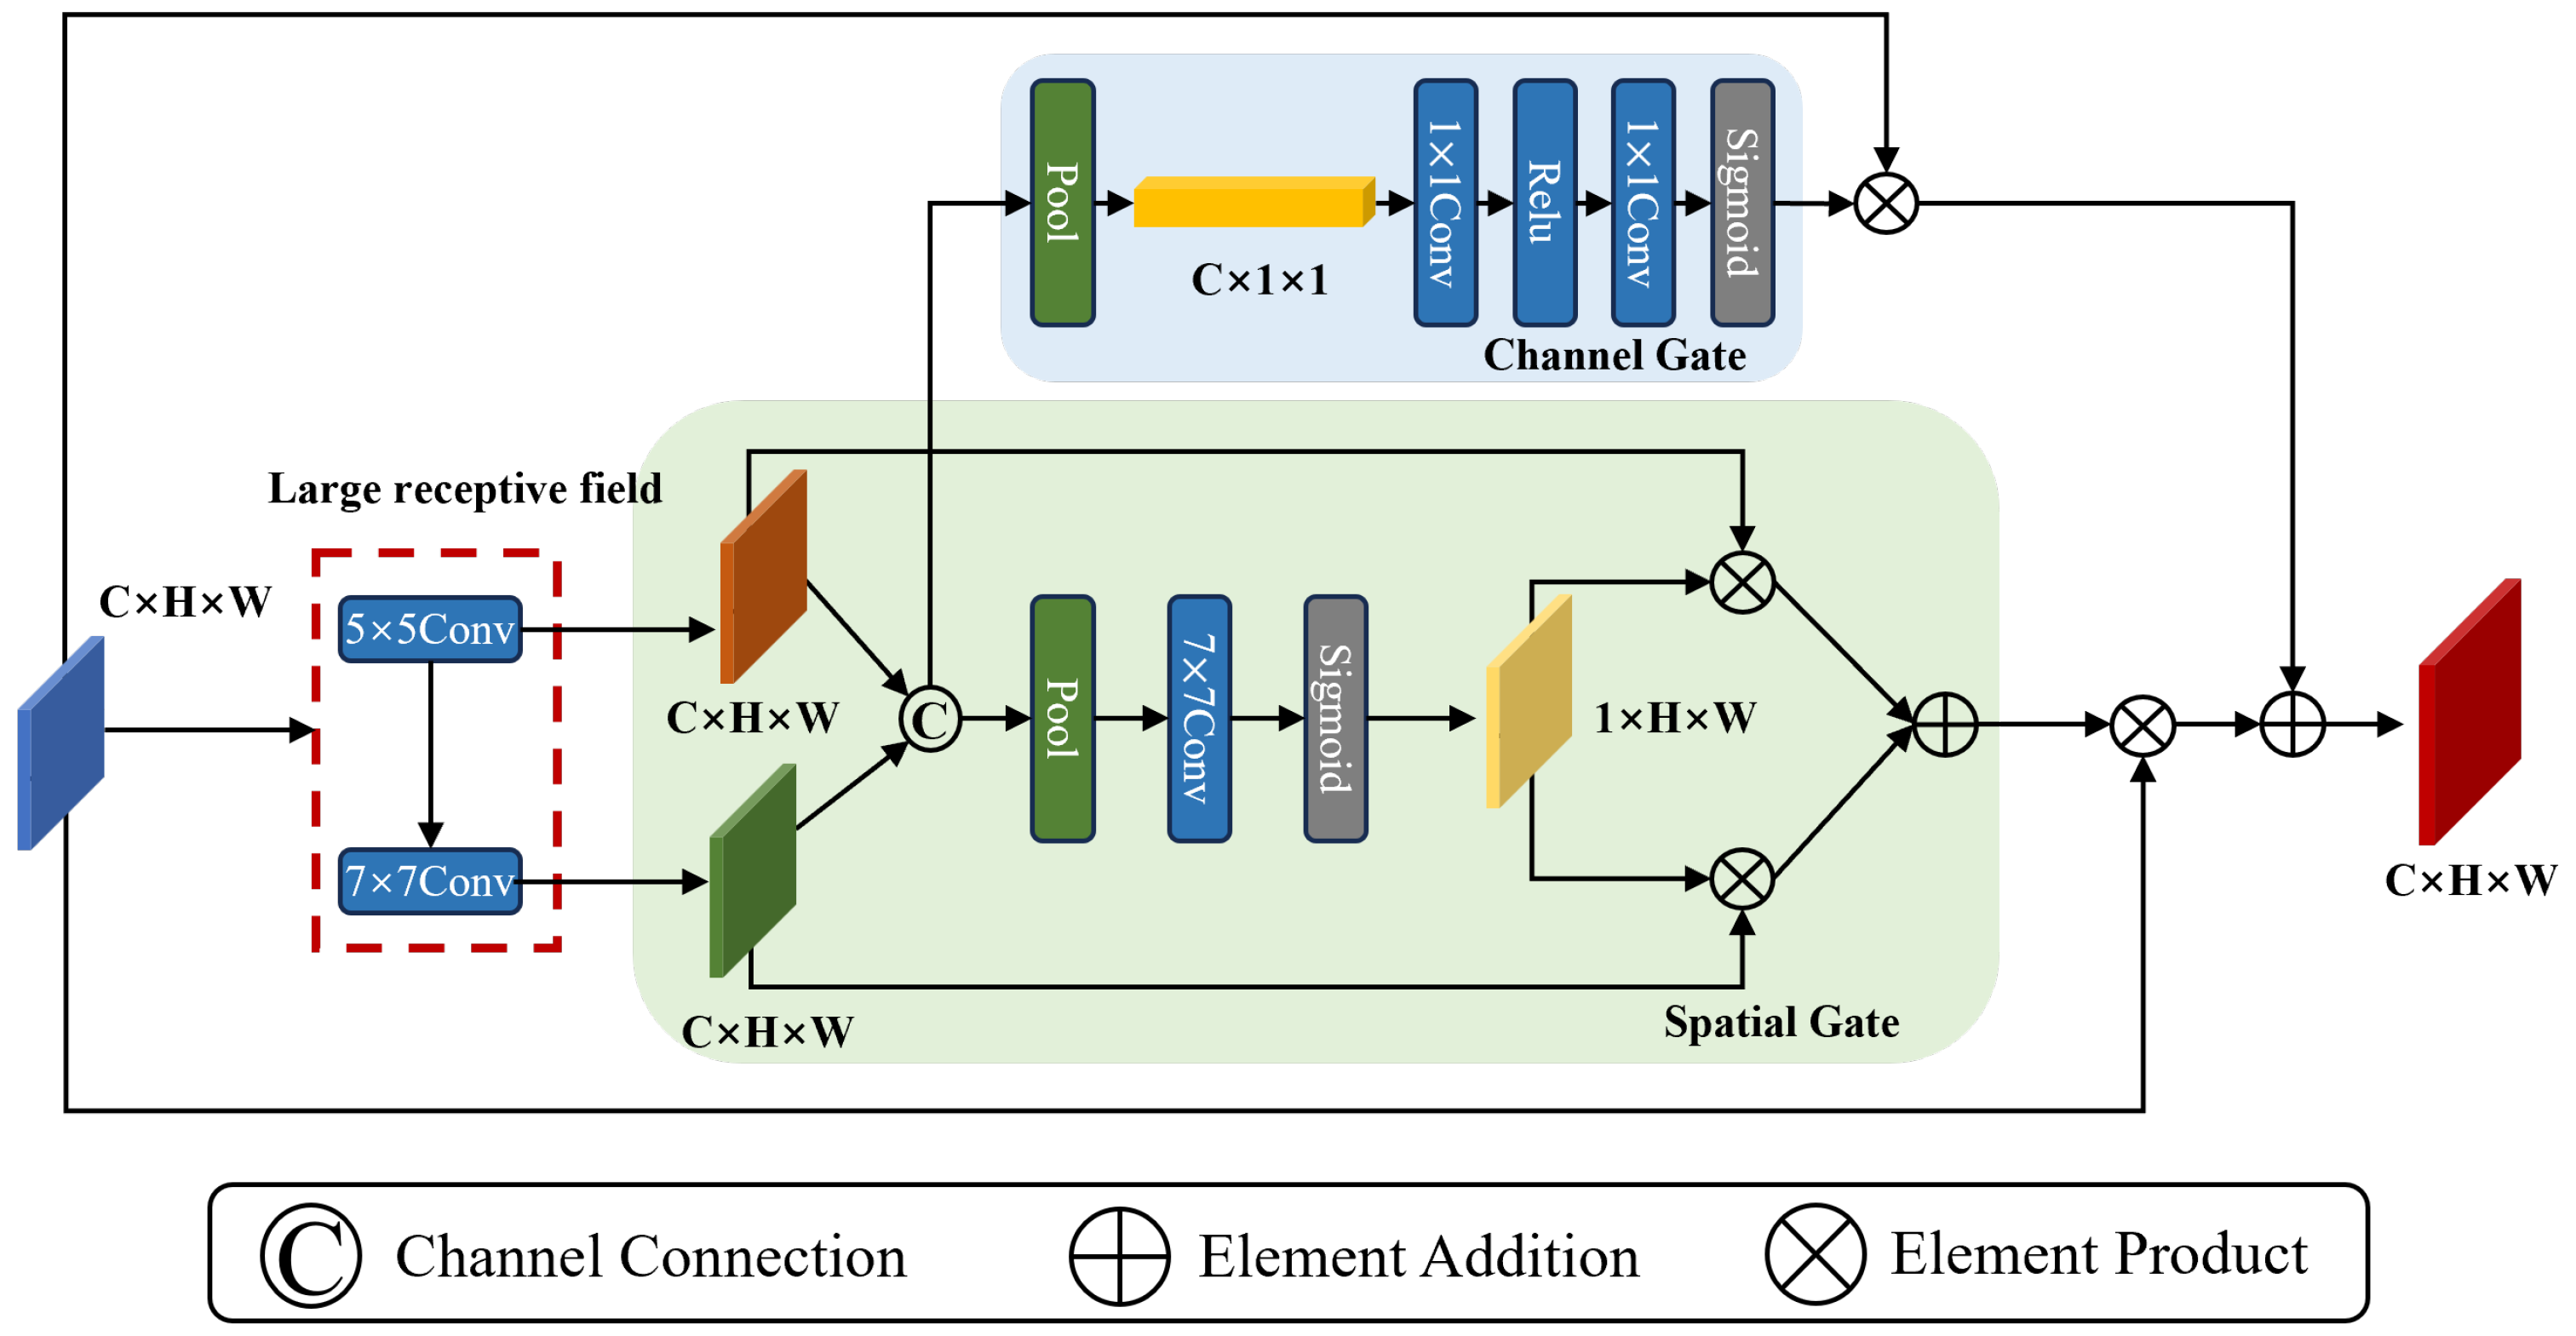
As illustrated in Figure 5, the Structural Repair Block (SRB) is designed to refine high-resolution decoder features by enlarging the receptive field while suppressing accumulated noise. Given an input feature map , SRB first adopts a lightweight large-kernel attention implemented by cascading small-kernel deep convolutions [13]:
where C denotes the channel number and H and W denote the spatial height and width, respectively; denotes a convolution, and denotes a dilated convolution with dilation rate .
Figure 5.
Structure of the Structural Repair Block (SRB).
For dilated convolution, the effective kernel size is
where k denotes the kernel size, d denotes the dilation rate, and is the resulting effective kernel size (receptive field) of the dilated convolution. This yields a substantially enlarged receptive field with .
The two branches are then compressed and fused by projections:
where denotes a convolution that projects features to channels, and indicates concatenation along the channel dimension.
Next, SRB applies spatial and channel gating in parallel. The spatial attention is computed from channel-wise average/max pooled maps:
where and denote channel-wise average pooling and max pooling, respectively; is the sigmoid activation; and denotes a convolution.
The channel attention is obtained by global average/max pooling followed by an MLP:
where and denote global average pooling and global max pooling, respectively; denotes a multi-layer perceptron; and is the sigmoid activation.
Finally, the gated features are fused and refined with a residual connection:
where ⊙ denotes the Hadamard (element-wise) product. is broadcast along the channel dimension, and is broadcast spatially.
3.5. Loss Function
Lite-BSSNet adopts a combined loss strategy during training, consisting of two parts: the main loss function for overall optimization and the auxiliary loss function for local supervision. The main loss function uses dice loss and cross-entropy loss, expressed as
where N represents the number of pixels, C represents the number of sample classes, represents the ground truth, and represents the probability that the i-th sample is predicted to be class c.
The auxiliary loss is computed using a cross-entropy loss and applied in the auxiliary head. The auxiliary head takes as input the fused features from the SBG module and two sets of VSS modules. Its output is produced through a 3 × 3 convolutional layer followed by batch normalization and ReLU activation and then a 1 × 1 convolutional layer and an upsampling operation. During training, the auxiliary loss is scaled by a weighting coefficient to balance the main loss and the auxiliary loss . Accordingly, the total loss is defined as
where is set to 0.4 [9] and is applied to an intermediate prediction head to stabilize optimization.
4. Experiment
4.1. Datasets
- (1)
- ISPRS Vaihingen: The Vaihingen dataset consists of 33 top image tiles with a spatial resolution of 9 cm, including RGB and near-infrared (NIR) bands, with an average size of 2500 × 2000 pixels. The images cover an urban area, and the scenes contain a variety of complex features, mainly divided into the following six classes: buildings, trees, low vegetation, vehicles, impervious surfaces, and miscellaneous objects. Following the same experimental protocol as UNetFormer [9], we select the following IDs: 2, 4, 6, 8, 10, 12, 14, 16, 20, 22, 24, 27, 29, 31, 33, 35, and 38 for testing, ID 30 for validation, and the remaining 15 images for training. The original image tiles are cropped to 1024 × 1024 pixels.
- (2)
- ISPRS Potsdam: The Potsdam dataset contains 38 top image tiles with a spatial resolution of 5 cm, including RGB and NIR bands, with an average size of 6000 × 6000 pixels. The dataset classes are the same as those of the Vaihingen dataset. Following the same experimental protocol as UNetFormer [9], we select the following IDs: 2_13, 2_14, 3_13, 3_14, 4_13, 4_14, 4_15, 5_13, 5_14, 5_15, 6_13, 6_14, 6_15, and 7_13 for testing, and ID 2_10 is used for validation. The remaining 22 images (except ID 7_10 with error annotations) are used for training. The original image tiles are cropped to 1024 × 1024 pixels.
4.2. Implementation Details
The model was implemented and trained using PyTorch 2.0.0 on a single NVIDIA RTX 4090 GPU. For the ISPRS Vaihingen and Potsdam datasets, the AdamW optimizer was adopted to ensure stable and accelerated convergence. The learning rate followed a cosine annealing schedule, starting from an initial value of . Images were cropped into 512 × 512-pixel patches and subjected to random scaling ([0.5, 0.75, 1.0, 1.25, 1.5]) and random horizontal and vertical flipping. Training was conducted for 100 epochs with a batch size of 8. During testing, test-time augmentation (TTA) strategies including multi-scale and random flipping were applied.
4.3. Evaluation Metrics
For quantitative analysis, three categories of evaluation metrics were used. The first class evaluates the segmentation performance. We used the overall accuracy (OA), mean F1 score (mF1), mean intersection over union (mIoU), mean boundary F1 score (mbF1), and mean centerline Dice score (mclDice). The meanings of these variables are provided by the following equations:
where , , , and represent the true positive, true negative, false positive, and false negative samples of the class k, respectively. For the boundary metric, and denote the boundary precision and boundary recall of class k.
To evaluate topological consistency, we additionally adopt clDice [53]. For class k, let and denote the predicted and ground-truth binary masks, and let be a skeletonization operator. The topological precision and recall are defined as
Accordingly, the mclDice over K classes is
The second class evaluates the scan-friendly properties of intermediate representations, which are important for Visual State Space (VSS) modeling. We adopt three indicators: total variation (TV), scan-wise variation (Scan), and scan-wise peak variation (Peak). Total variation measures spatial smoothness of feature maps and is defined as
where is a feature map and denotes the value at channel c and location .
To assess suitability for sequential scanning, the feature map is flattened into a 1D sequence following a fixed raster scan order. The scan-wise variation and scan-wise peak variation are defined as
where denotes the empirical mean over all valid indices. X is flattened into a 1D sequence in row-major order, where .
For comparison, we present the reduction ratio (after/before) of these metrics, where lower values indicate smoother and more scan-friendly representations.
The third class evaluates the memory requirements and running speed of the model. Memory requirements are measured by the number of model parameters (P), while running speed is evaluated by the number of floating point operations (FLOPs) and the frames per second (FPS).
4.4. Performance Comparison and Visualization
In this experiment, we selected several SOTA semantic segmentation methods and conducted a comprehensive comparison on the ISPRS Vaihingen and Potsdam datasets. The compared methods include CNN-based models: ABCNet [36], SwiftNet [54], and PACSCNet [55]; Transformer-based models: Segmenter [56], BANet [57], and HST-UNet [58]; Mamba-based models: RS3Mamba [21], UNetMamba [22], Samba [44], PPMamba [59], and PyramidMamba [60]; hybrid-based models: UNetFormer [9], CMLFormer [10], UrbanSSF-T [20], and UMFormer [46].
- (1)
- Results on the ISPRS Vaihingen dataset
The ISPRS Vaihingen dataset has been widely adopted for semantic segmentation tasks owing to its high-resolution imagery, diverse object categories, and high-quality annotations. As shown in Table 1, Lite-BSSNet achieves the highest mIoU (83.9%) and mF1 (91.1%) on the Vaihingen test set, surpassing existing CNN-, ViT-, Mamba-, and hybrid-based models. Notably, Lite-BSSNet maintains high segmentation accuracy while achieving competitive performance in terms of memory and computational efficiency. The total number of parameters (12.3 M) is second only to the lightweight model UNetFormer, whereas the FLOPs (45.4 G) are the lowest among all compared models. These results indicate that Lite-BSSNet not only delivers superior classification performance but also achieves an optimized balance between memory consumption and computational efficiency. Furthermore, the lightweight design of Lite-BSSNet enables efficient operation under resource-constrained and real-time conditions, leading to improvements in processing efficiency and reductions in inference latency, suggesting the possibility of practical deployment.
Table 1.
Results on the ISPRS Vaihingen test dataset, where “—” denotes missing values. Bold and underlined text represent the best and second-best results, respectively. “↑” indicates better results with higher values.
However, the overall accuracy (OA) of Lite-BSSNet did not reach the highest level, which may be because OA primarily reflects the overall proportion of correctly classified pixels and is heavily influenced by dominant classes. In contrast, Lite-BSSNet achieves relatively balanced performance across all classes, maintaining consistent accuracy rather than favoring dominant categories. By comparison, UrbanSSF-T exhibits exceptionally high accuracy in the Impervious Surface (ImSurf) class, which disproportionately elevates its overall OA score.
- (2)
- Results on the ISPRS Potsdam dataset
To further evaluate the effectiveness of Lite-BSSNet, we also performed experiments on the ISPRS Potsdam dataset, using a processing method similar to that of the ISPRS Vaihingen dataset. Unlike the ISPRS Vaihingen dataset, the ISPRS Potsdam dataset has higher image resolution and point-cloud density, making it suitable for finer-grained feature classification. As shown in Table 2, Lite-BSSNet achieved the highest mIoU (86.7%) and mF1 (92.7%) on the Potsdam test dateset. It should be noted that our method achieved an F1 score of 88.3% in the low vegetation class, exceeding other networks by more than 0.3%.
Table 2.
Results on the ISPRS Potsdam test dataset, where “—” denotes missing values, bold and underlined text represent the best and second-best results, respectively. “↑” indicates better results with higher values.
- (3)
- Visualization of segmentation results
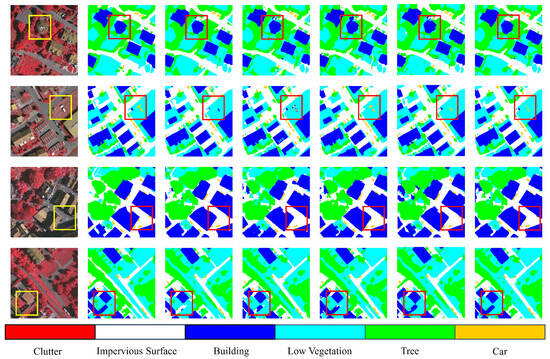
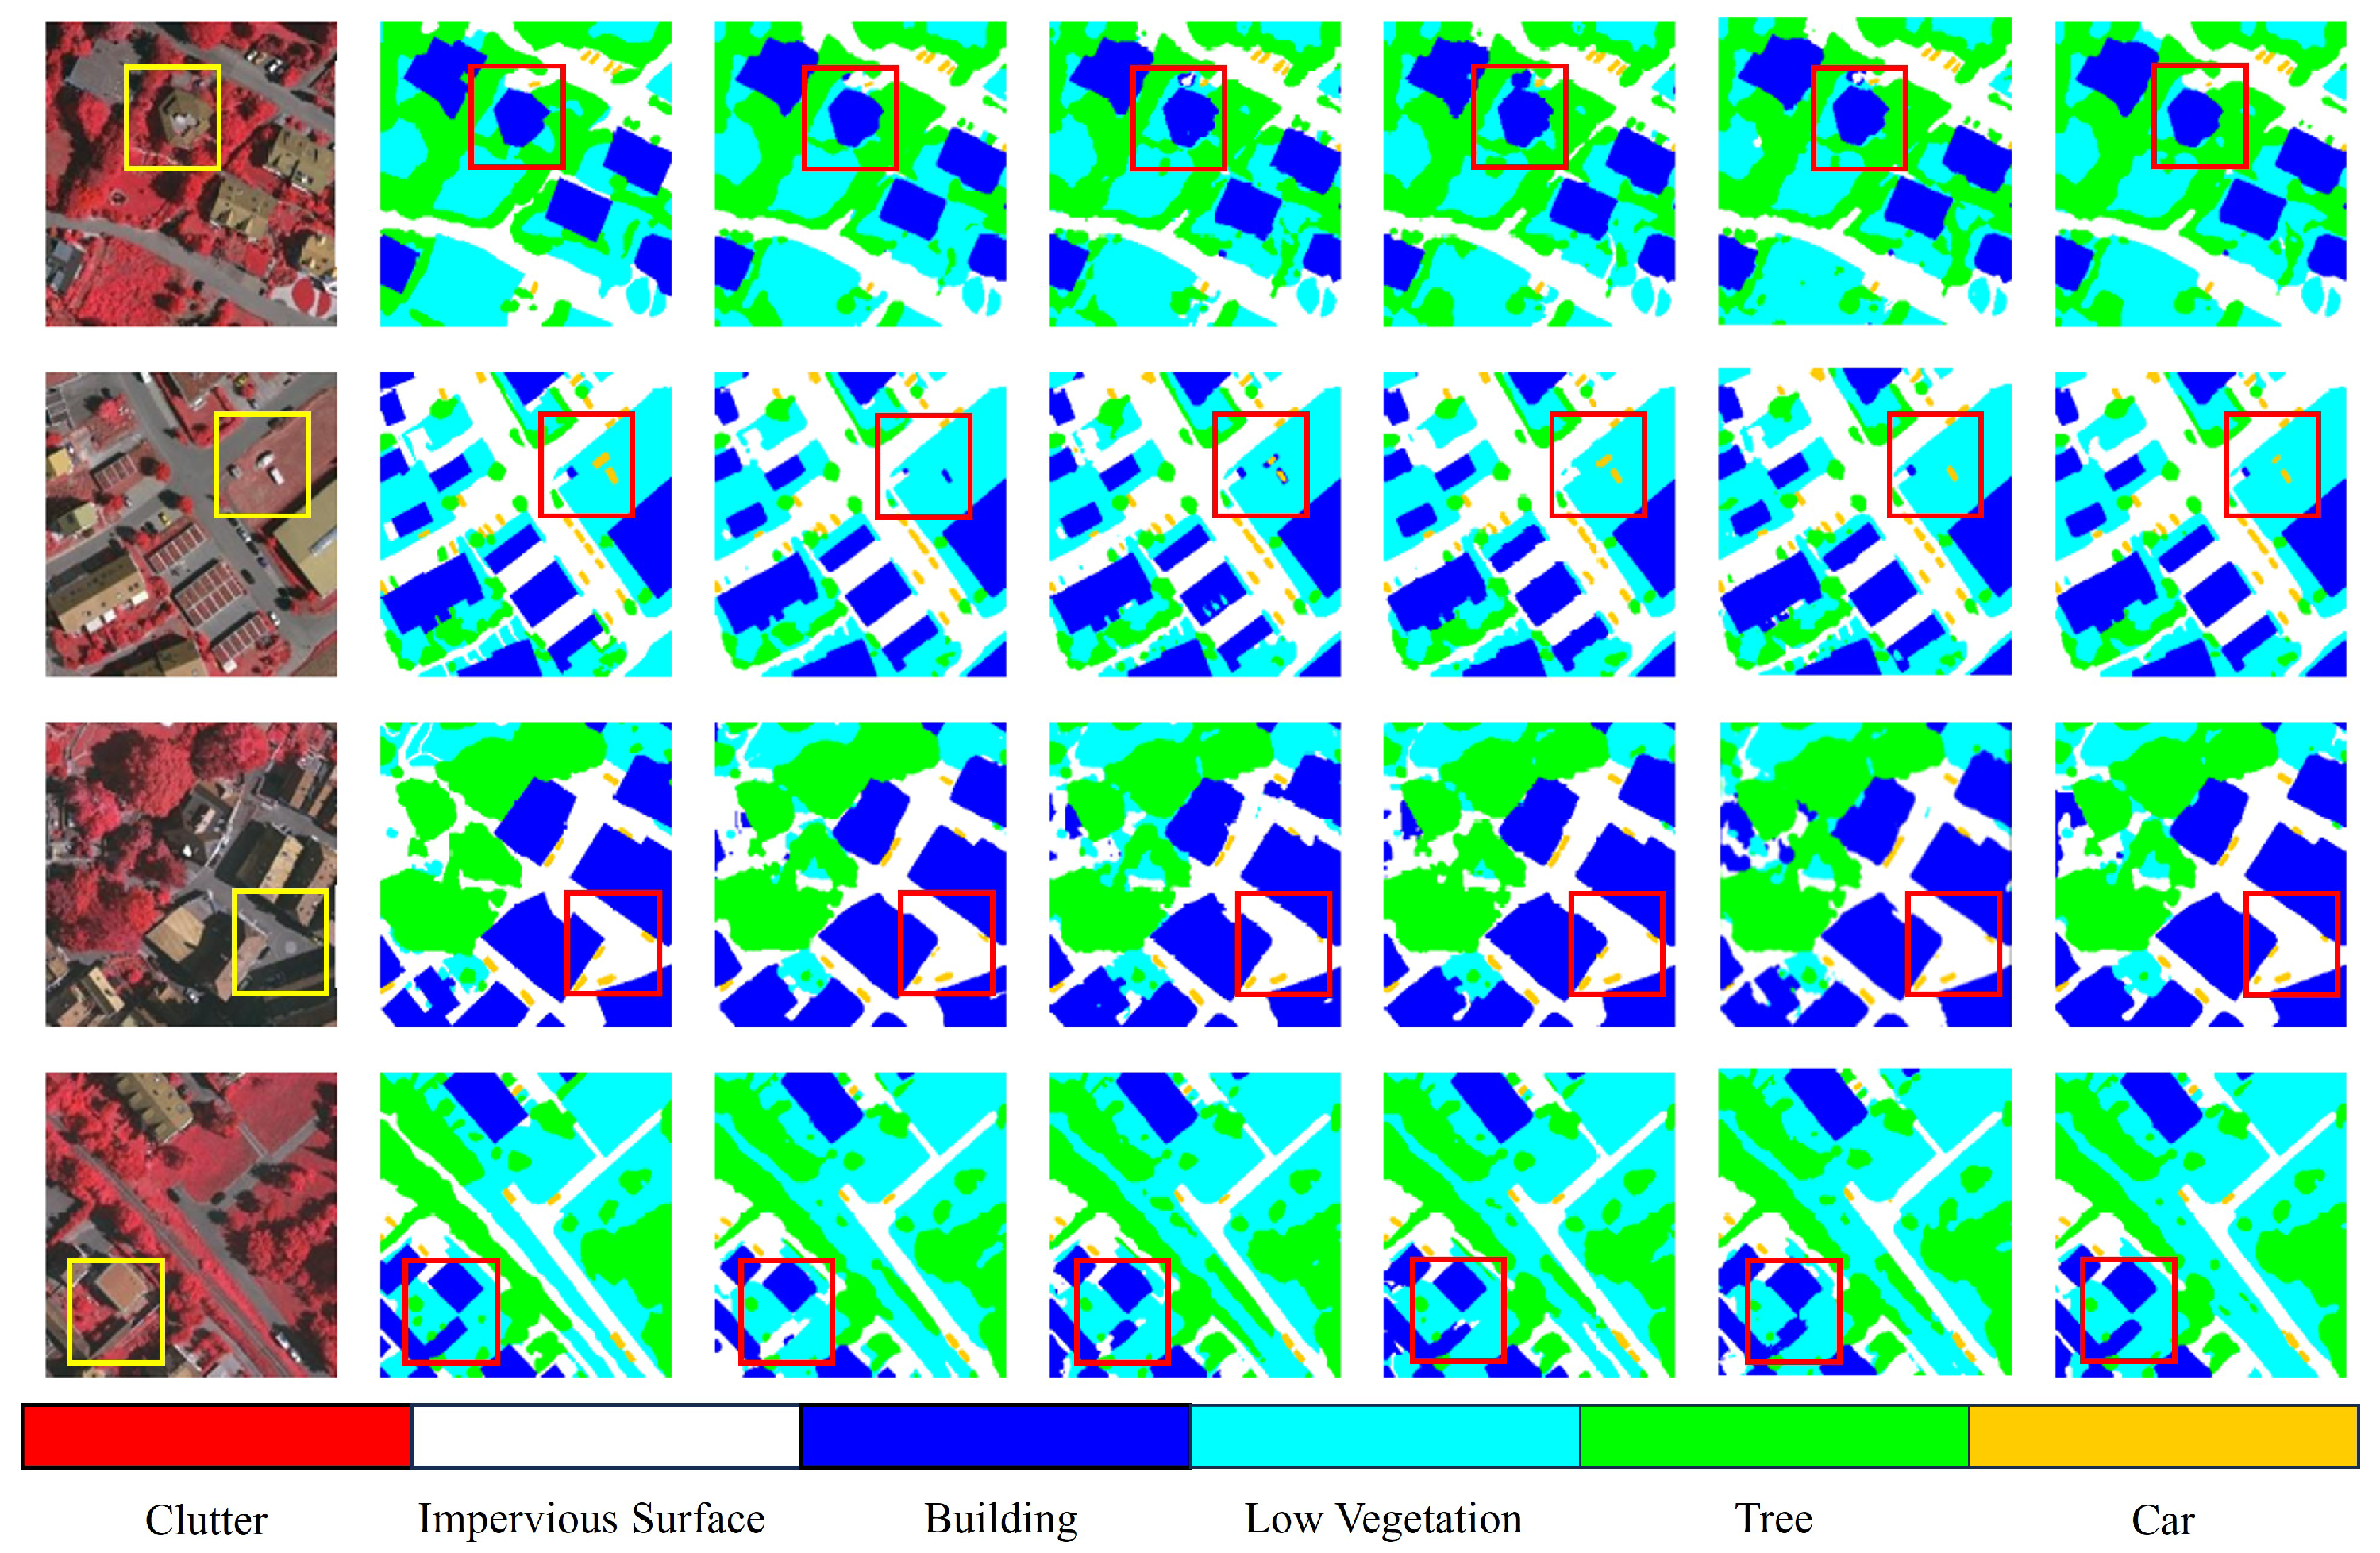
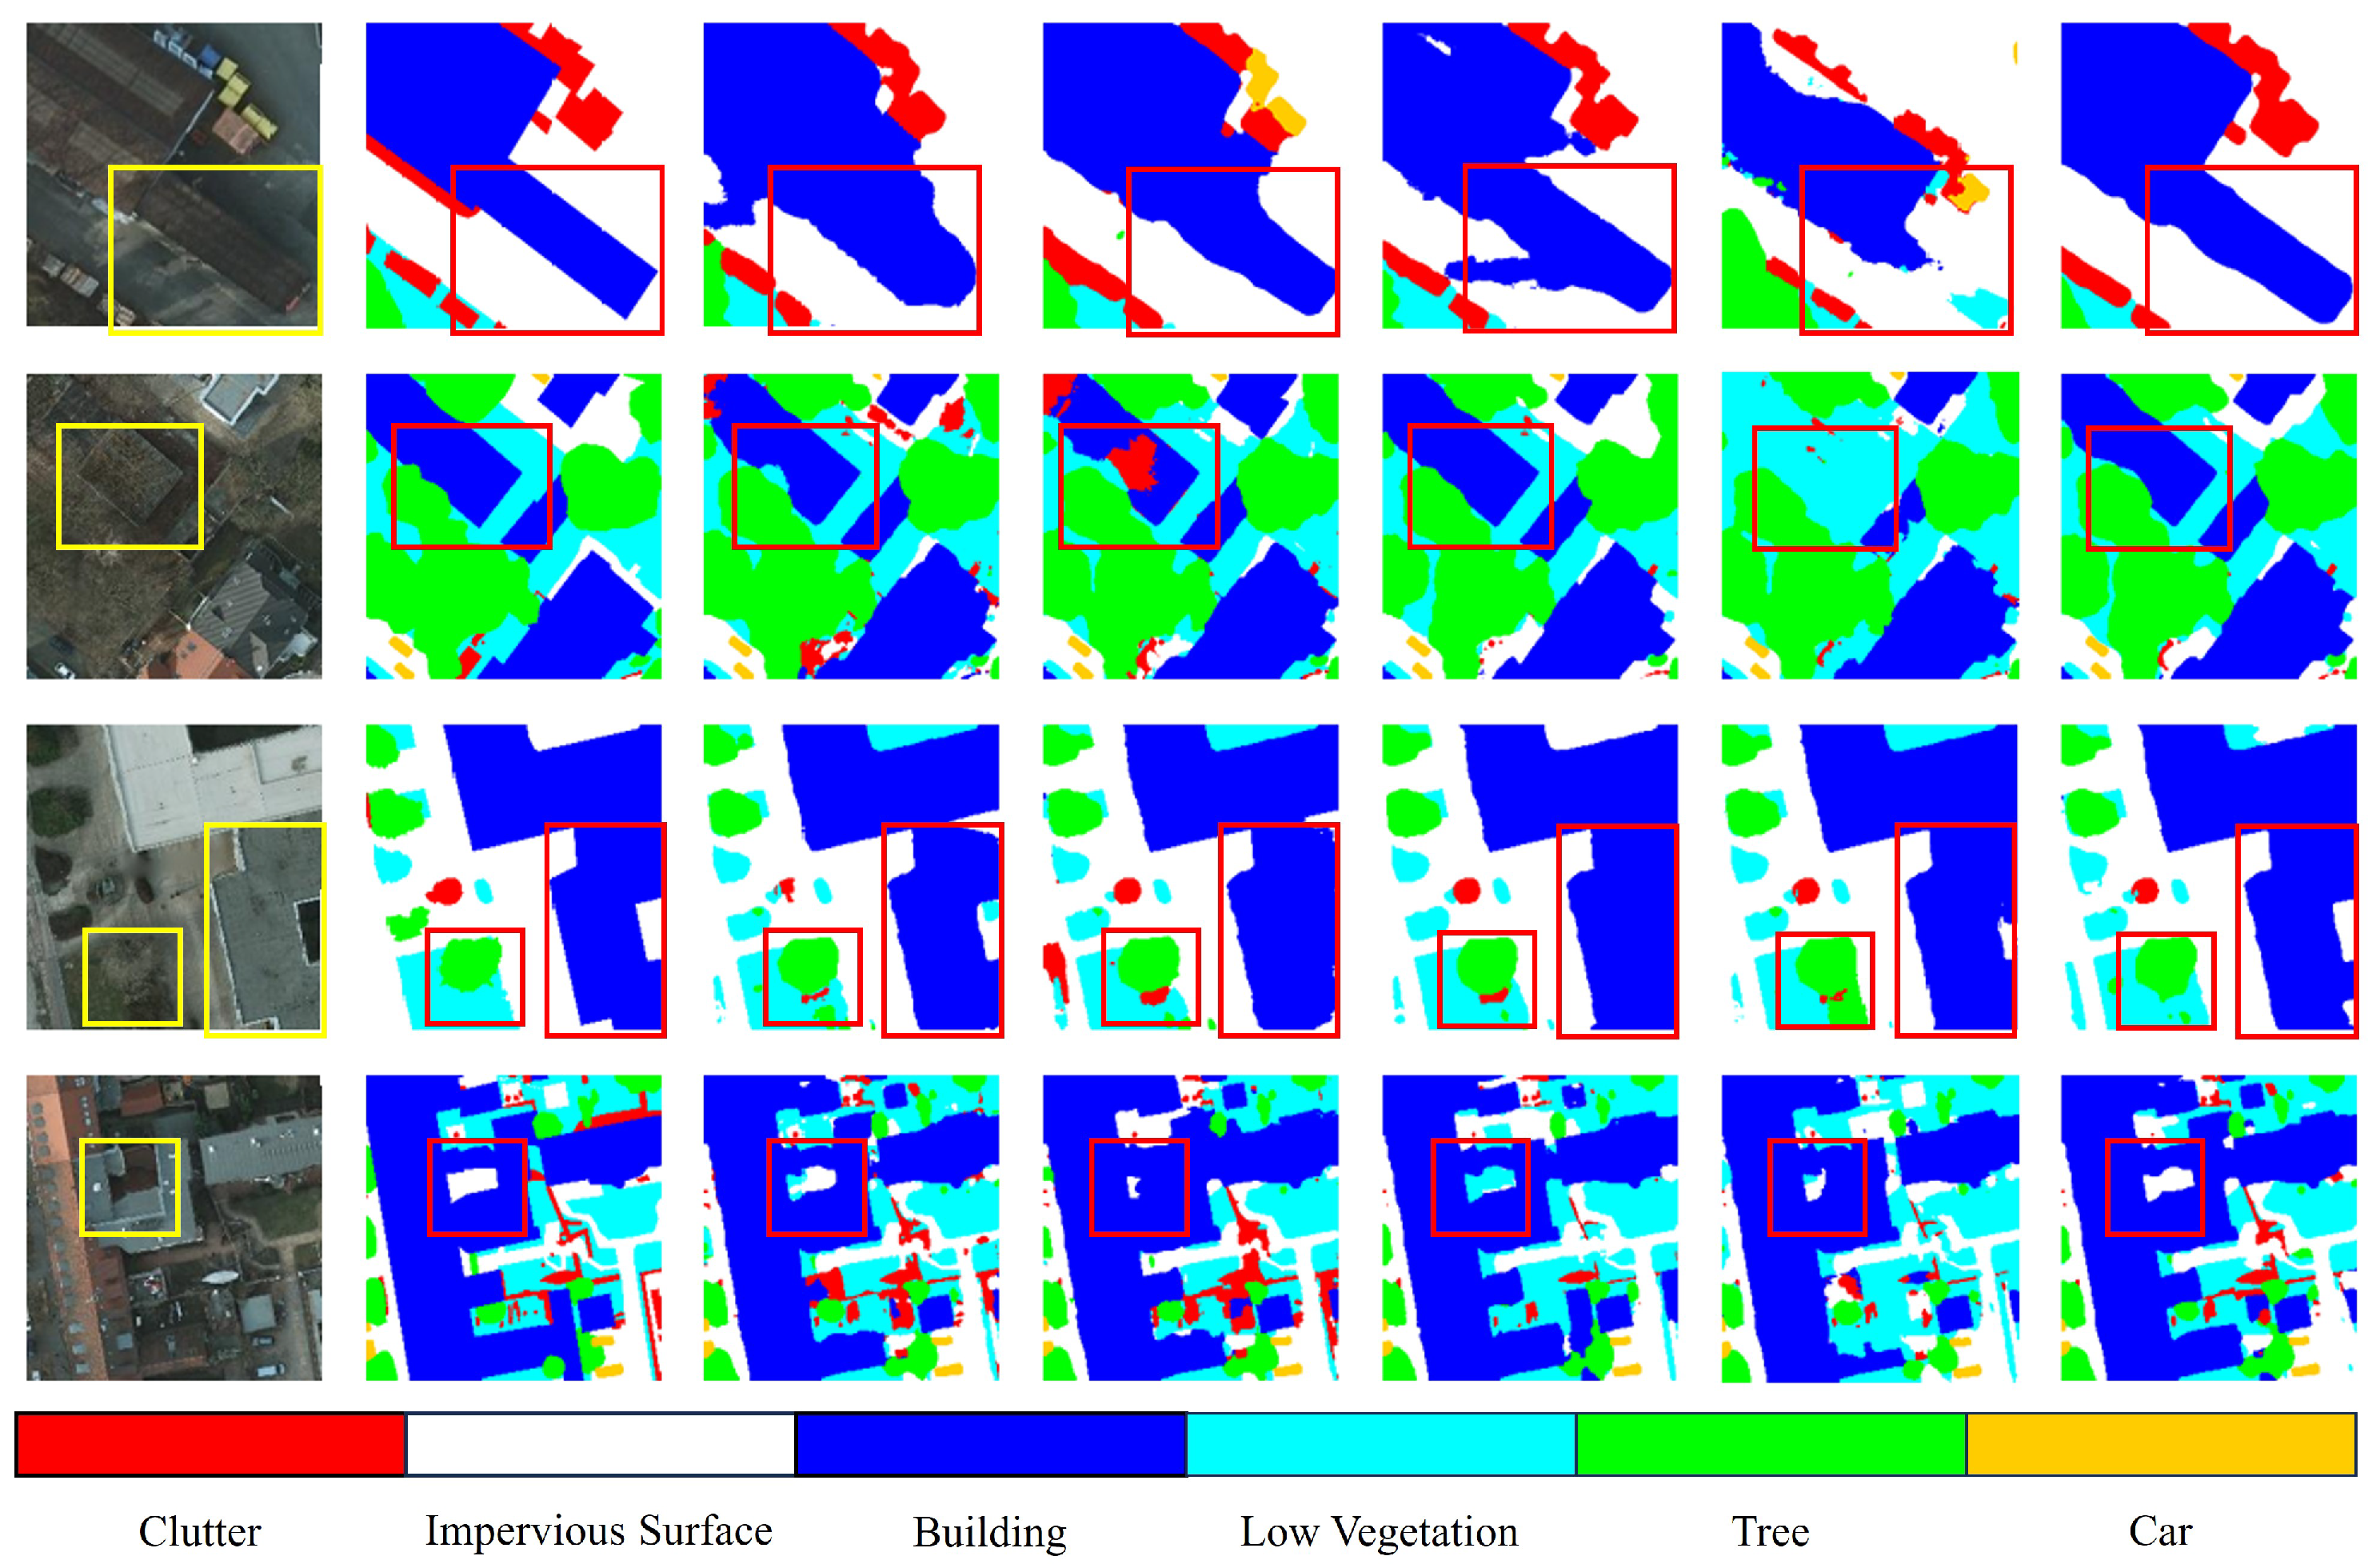
To enhance the interpretability of Lite-BSSNet, the segmentation results on the Vaihingen and Potsdam datasets are visualized, as shown in Figure 6 and Figure 7. The red areas highlight challenging object regions. By comparing the visualizations, it is evident that Lite-BSSNet produces more accurate segmentation results in challenging regions and generates outputs closer to the ground truth than other models. These results suggest that Lite-BSSNet exhibits a stronger capability to capture fine details and accurately delineate complex object boundaries, even in the presence of occlusions and high-reflectance surfaces.
Figure 6.
Semantic segmentation results on the ISPRS Vaihingen test set, from left to right: original image, ground truth, ABCNet [36], UNetFormer [9], UNetMamba [22], UMFormer [46], and Lite-BSSNet. The colored bounding boxes highlight representative regions for visual comparison (yellow: input images; red: segmentation maps).
Figure 7.
Semantic segmentation results of the ISPRS Potsdam test set, from left to right: original image, ground truth labels, ABCNet [36], UNetFormer [9], UNetMamba [22], UMFormer [46], and Lite-BSSNet. The colored bounding boxes highlight representative regions for visual comparison (yellow: input images; red: segmentation maps).
4.5. Efficiency Analysis
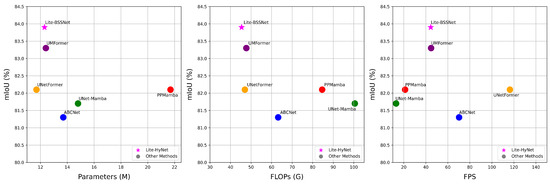
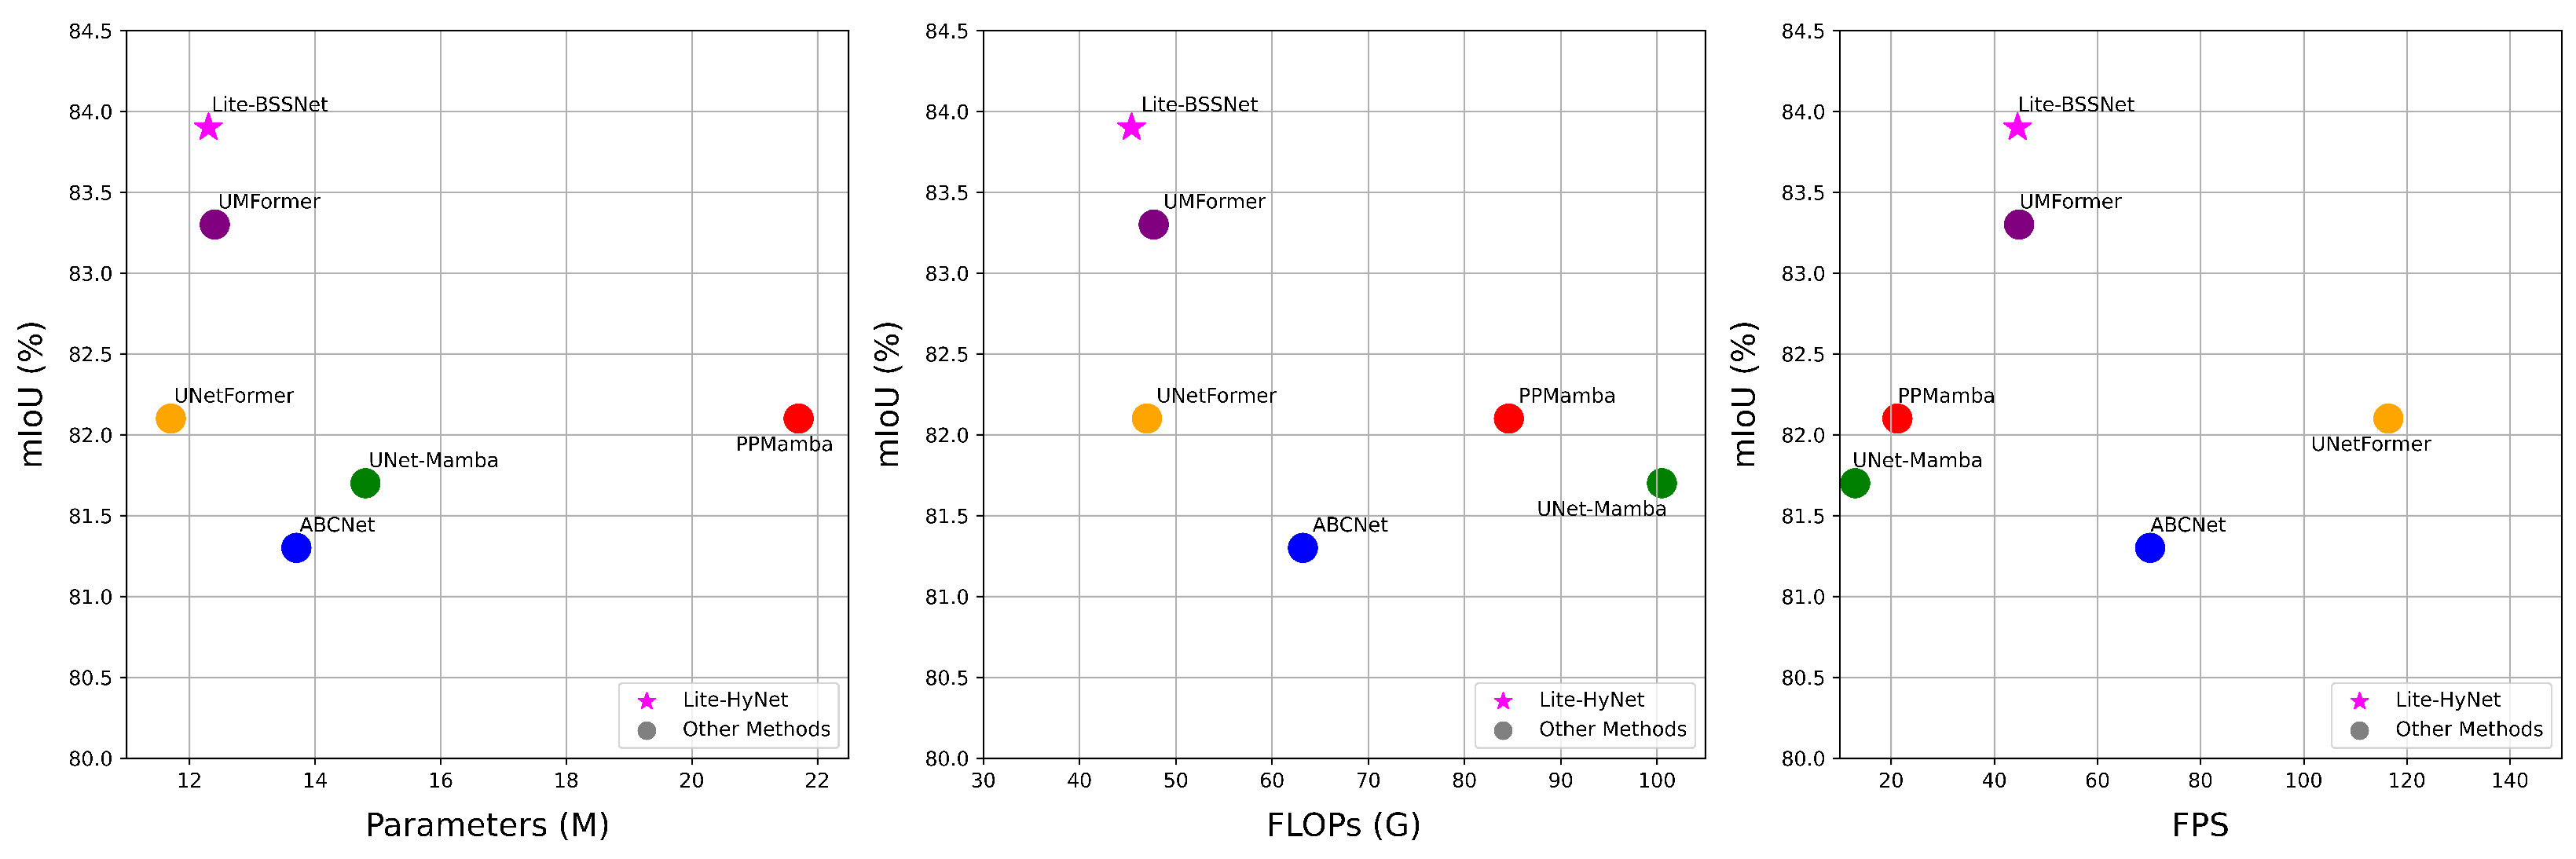
Model complexity and runtime speed are crucial metrics for evaluating segmentation performance, particularly in resource-constrained environments where accurate real-time or near-real-time performance is essential. The performance of Lite-BSSNet on the Vaihingen dataset is summarized in Figure 8. The results show that Lite-BSSNet improves both accuracy and computational efficiency without increasing the parameter count, achieving the highest mIoU (83.9%) and the lowest 45.4 GFLOPs among compared models. Specifically, compared with single-decoder architectures, Lite-BSSNet achieves an average mIoU improvement of 2.2% and a FLOPs reduction of 37.4 G. When compared with existing lightweight hybrid decoder models, it achieves an additional 1.2% improvement in mIoU while maintaining a similar computational cost. The results suggest that Lite-BSSNet achieves a reasonable balance between segmentation accuracy and computational efficiency, showing potential for real-time applications.
Figure 8.
Visualization of comparison results against SOTA lightweight networks. Complexity and speed are measured based on performance on a single NVIDIA RTX 4090 GPU processing with an input size of 1024 × 1024.
However, Lite-BSSNet does not achieve the highest performance in terms of frames per second (FPS). This limitation may result from Mamba’s selective state mechanism, which dynamically adjusts parameters based on input characteristics. Although this mechanism enhances the model’s adaptability and feature representation capability, it inevitably constrains real-time processing efficiency.
4.6. Ablation Experiment
- (1)
- The role of each component
To evaluate the contribution of each core component in Lite-BSSNet, we take the full model as the baseline and conduct a series of ablation experiments on the ISPRS Vaihingen and Potsdam test sets. Specifically, we examine the effectiveness of the three key modules in the decoder: the Structural Blueprint Generator (SBG), the Visual State Space Bridge (VSS-Bridge), and the Structural Repair Block (SRB). By selectively enabling or disabling these modules, we obtain eight model variants that cover all possible combinations, as reported in Table 3.
Table 3.
Ablation experiment results on the ISPRS Vaihingen and Potsdam test datasets; the best result is shown in bold. Symbols “×” and “✓” indicate the exclusion and inclusion of specific modules, respectively. “↑” indicates better results with higher values.
As shown in Table 3, introducing any single module leads to consistent improvements on both datasets. In particular, enabling VSS-Bridge alone yields a larger gain than using SBG or SRB alone. Specifically, incorporating VSS-Bridge independently increases mIoU by 1.0% and 0.4% across the Vaihingen and Potsdam datasets, highlighting the importance of cross-layer alignment and state-space-aware feature projection. SBG and SRB also deliver significant benefits by enhancing high-level structural priors and optimizing structural refinement, respectively. Combining two modules consistently yields additional gains. For example, using VSS-Bridge and SRB together increases mIoU from 82.1% to 83.6% on Vaihingen and from 84.9% to 86.6% on Potsdam. The best results are obtained when all three components are enabled: Lite-BSSNet achieves mIoU scores of 83.9% and 86.7% on the Vaihingen and Potsdam datasets, respectively, along with the highest mF1 and overall accuracy (OA). Overall, these results validate the effectiveness of the proposed blueprint–bridge–repair decoding pipeline and confirm that each module contributes to the final performance.
- (2)
- Effectiveness of the blueprint–bridge–repair hybrid decoding structure
To evaluate the effectiveness of the proposed Lite-BSSNet blueprint–bridge–repair hybrid decoding structure, we replaced its decoder with different single-architecture decoders and conducted experiments on the Vaihingen dataset. Specifically, three types of decoders were compared: a CNN-based decoder (U-Net [7]), a Transformer-based decoder (Swin-UNet [61]), and a Mamba-based decoder (UNetMamba [22]). As shown in Table 4, Lite-BSSNet’s hybrid decoder achieves the highest segmentation accuracy, with an mIoU value of 83.9%, averaging approximately 1.2% higher than the three single-architecture decoders. Notably, this improvement does not incur a significant computational burden: Lite-BSSNet requires only 45.4 GFLOPs and attains an inference speed of 44.5 fps, indicating a favorable balance between performance and efficiency.
Table 4.
Results of different decoders on the Lite-BSSNet model for the ISPRS Vaihingen test dataset. “↑” indicates higher is better, while “↓” indicates lower is better.
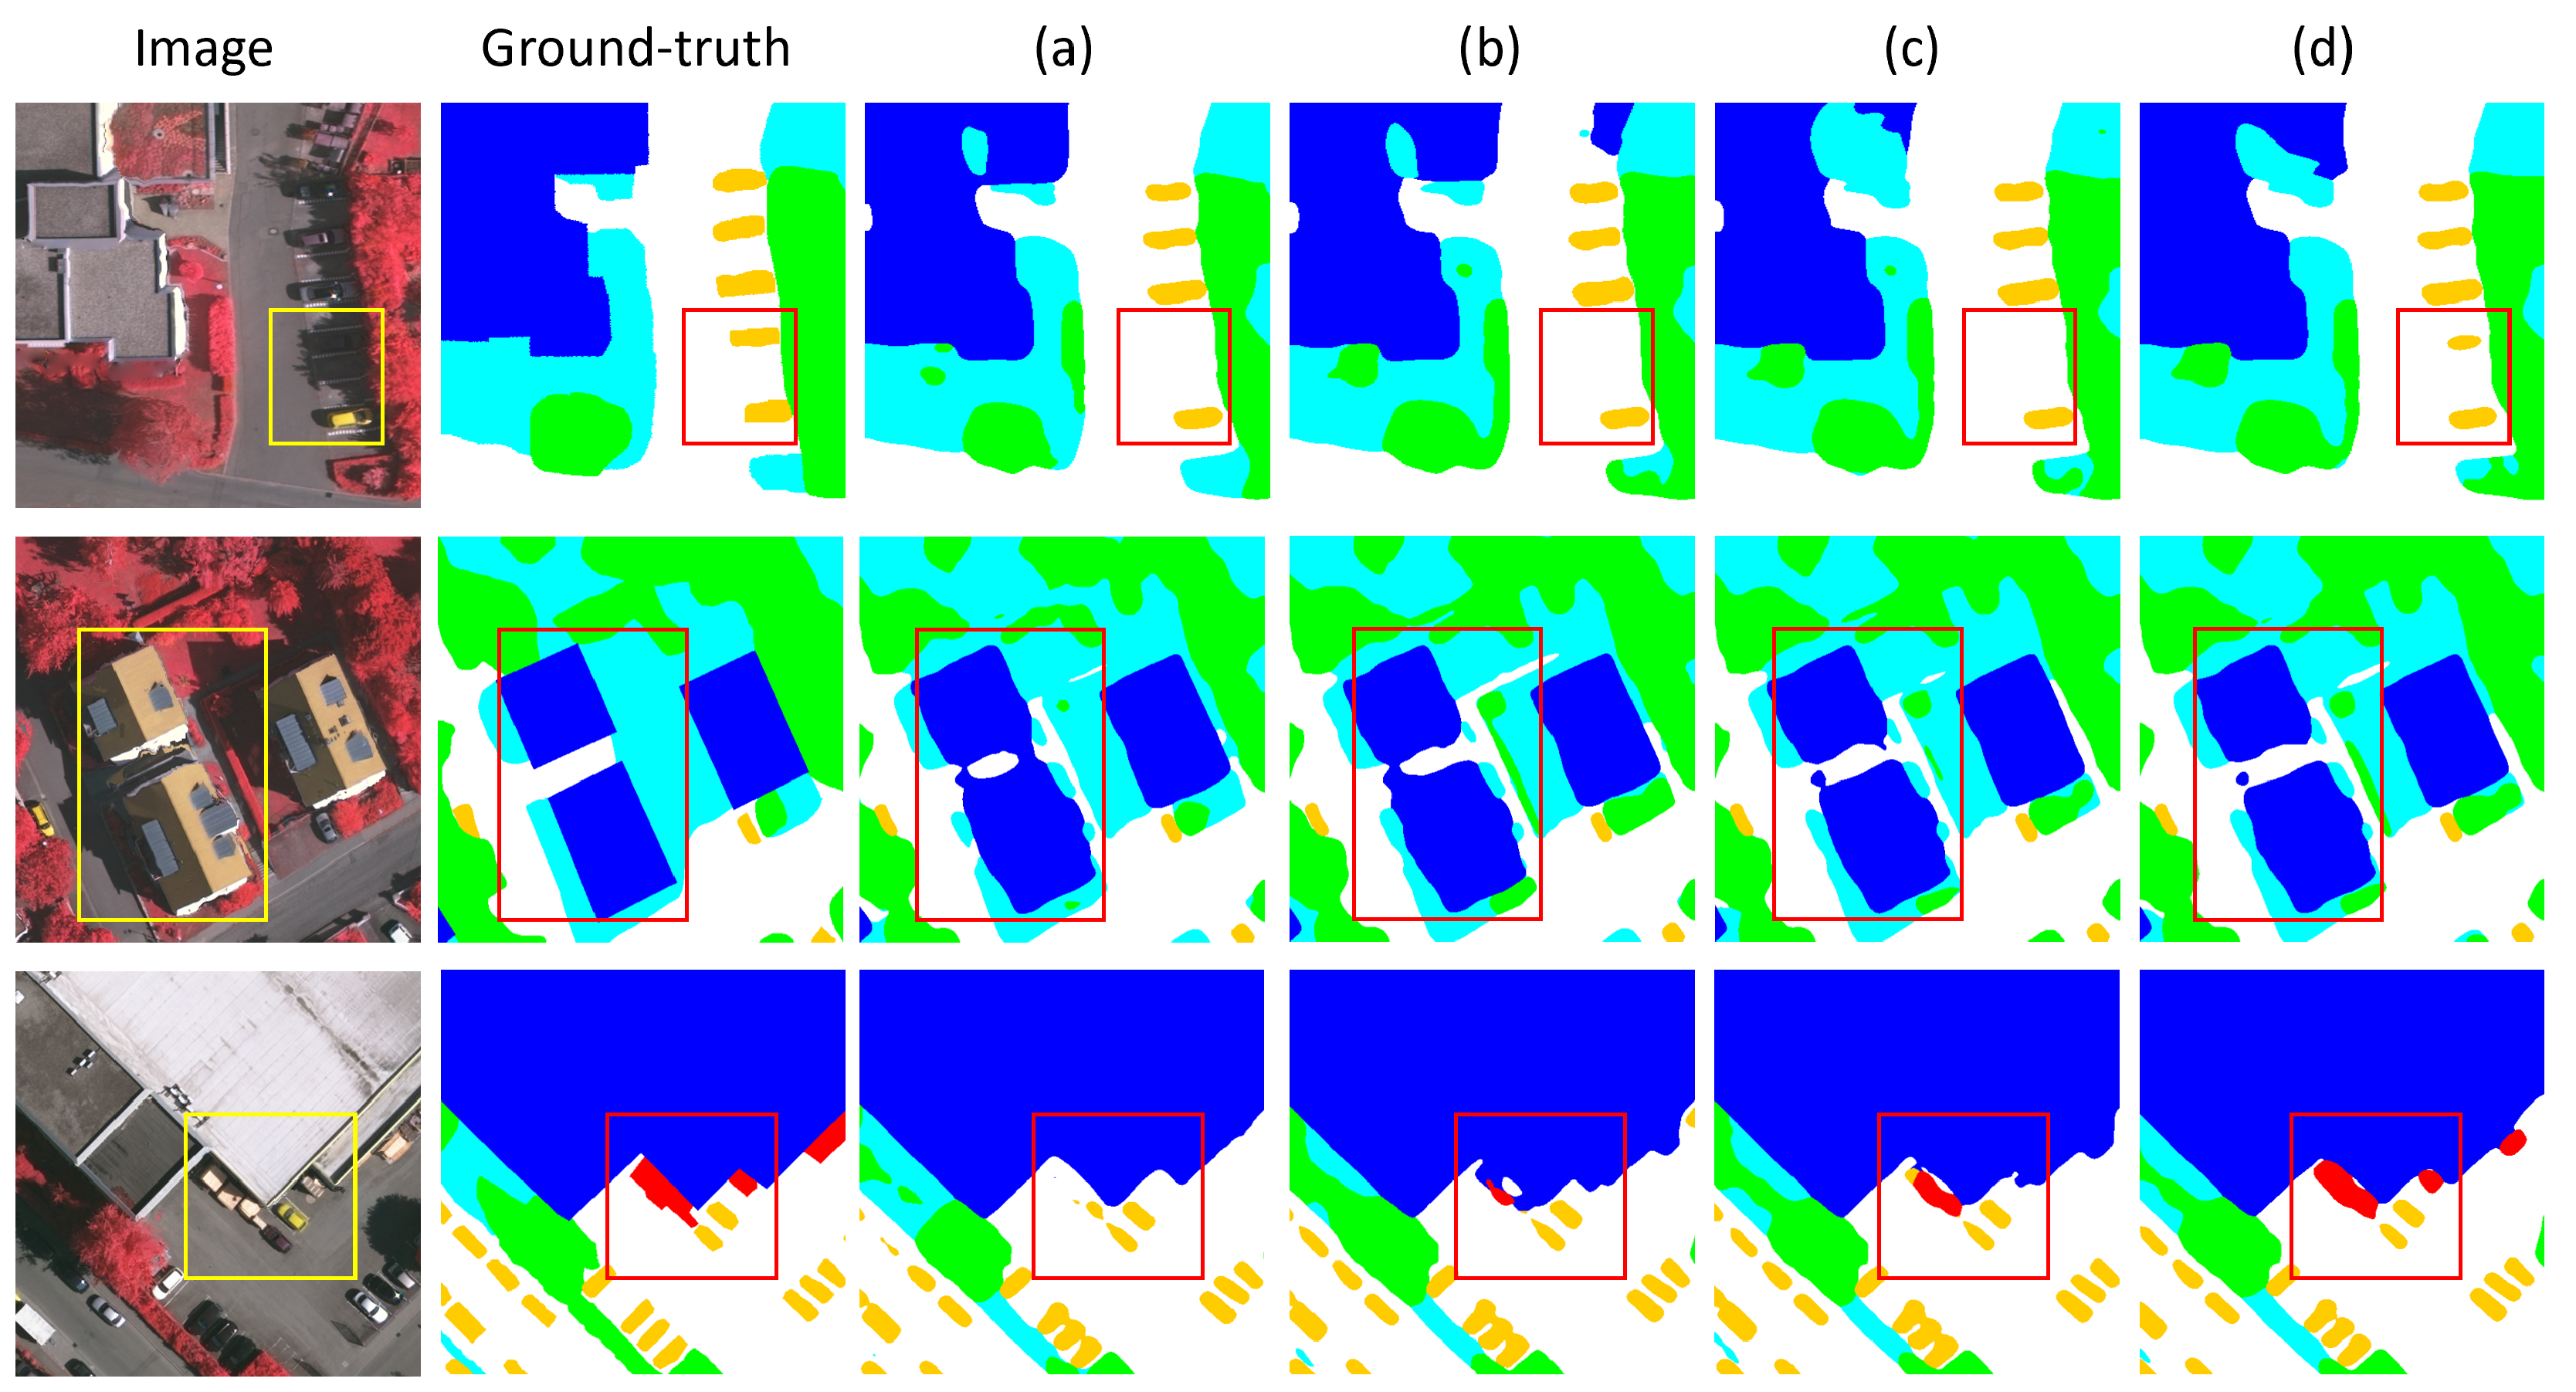
Furthermore, the visual comparison of segmentation results (as shown in Figure 9) shows that Lite-BSSNet more accurately identifies small and partially occluded objects compared with single-architecture decoders. This suggests that the blueprint–bridge–repair decoding pipeline is effective. It combines CNN-style local operators, visual state space modeling, and structural repair. As a result, the model captures global context while preserving local sensitivity, enabling precise recognition of fine-grained targets in complex scenes.
Figure 9.
Semantic segmentation results of the Lite-BSSNet model using different decoders. (a) CNN based. (b) Transformer based. (c) Mamba based. (d) Lite-BSSNet hybrid decoding. The colored bounding boxes highlight representative regions for visual comparison (yellow: input images; red: segmentation maps).
In summary, the proposed Lite-BSSNet hybrid decoder significantly improves segmentation accuracy while maintaining high computational efficiency, validating the rationality and effectiveness of its design for remote sensing semantic segmentation.
- (3)
- Comparison of bridge feature interaction modules
To further evaluate the effectiveness of the proposed Visual State Space Bridge (VSS-Bridge), we compare it with several alternative cross-layer feature interaction mechanisms: (1) directly concatenating cross-layer features (“Concat”); (2) replacing VSS-Bridge with the SEA module from SeaFormer [62] (“SEA”); (3) replacing it with the WS module from UNetFormer [9] (“WS”); and (4) replacing it with the DMCA module from SparX [24] (“DMCA”). As shown in Table 5, VSS-Bridge achieves the best overall segmentation performance on both the Vaihingen and Potsdam test sets. All interaction-based alternatives outperform the “Concat” baseline, supporting the benefit of explicit cross-layer interaction over naive feature aggregation.
Table 5.
Experimental results of the bridge feature interaction module on the ISPRS Vaihingen and Potsdam test datasets; the best result is shown in bold. “↑” indicates higher is better, while “↓” indicates lower is better.
Beyond segmentation accuracy, we further examine the scan-friendly properties of the resulting representations using three indicators: total variation (TV), scan-wise variation, and scan-wise peak variation. As shown in Table 6, “Concat” yields the largest ratios across all three metrics, reflecting substantial spatial and sequential discontinuities. In contrast, all interaction modules reduce these ratios, with VSS-Bridge consistently achieving the lowest values. This suggests that VSS-Bridge suppresses both average and worst-case token-to-token variations along the scan order. As a result, the representations are better conditioned for the streaming nature of visual state space modeling.
Table 6.
Comparison of scan-friendly properties for different interaction modules; ratios are computed as after/before, and lower is better; the best result is shown in bold. “↓” indicates lower is better.
Notably, DMCA attains competitive reductions but remains less effective on the peak metric, indicating weaker control over worst-case transitions. A plausible explanation is that DMCA relies on fixed spatial interaction patterns, whereas VSS-Bridge leverages dynamic axial attention to adapt cross-layer alignment to diverse structural layouts in remote sensing scenes, improving robustness without introducing significant additional parameters or computational overhead.
- (4)
- Selection of SRB receptive field size
ConvNet [12] demonstrated that enlarging convolutional kernel sizes can effectively strengthen long-range dependency modeling and improve a model’s expressive capability. Following this principle, we evaluate how different receptive field configurations within the proposed Structural Repair Block (SRB) influence the performance of Lite-BSSNet.
We, therefore, compare models configured with SRB receptive fields equivalent to kernel sizes of 5, 11, 23, and 29, along with a baseline in which SRB is removed entirely. Experiments are conducted on both the ISPRS Vaihingen and Potsdam test sets. As reported in Table 7, a receptive field of 23 achieves the best overall performance. Enlarging the receptive field generally enhances segmentation accuracy because wider spatial support enables SRB to better correct upsampling-induced distortions and preserve long, thin structures. However, excessively increasing the receptive field yields diminishing performance gains while introducing additional computational overhead. This result suggests that extremely large kernels do not further improve the structural repair process and may even reduce computational efficiency. Overall, these findings confirm that a moderate large-kernel configuration, such as a receptive field of 23, provides the most effective balance between structural repair strength, gradient smoothing for VSS modeling, and computational efficiency.
Table 7.
Experimental results of SRB with different receptive fields on the ISPRS Vaihingen and Potsdam test datasets; the best result is shown in bold. “—” indicates a missing value. “√” indicates inclusion of specific modules. “↑” indicates higher is better, while “↓” indicates lower is better.
- (5)
- Interpretability of the SBG
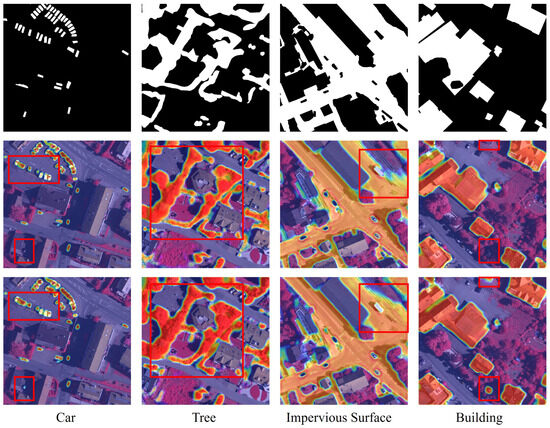
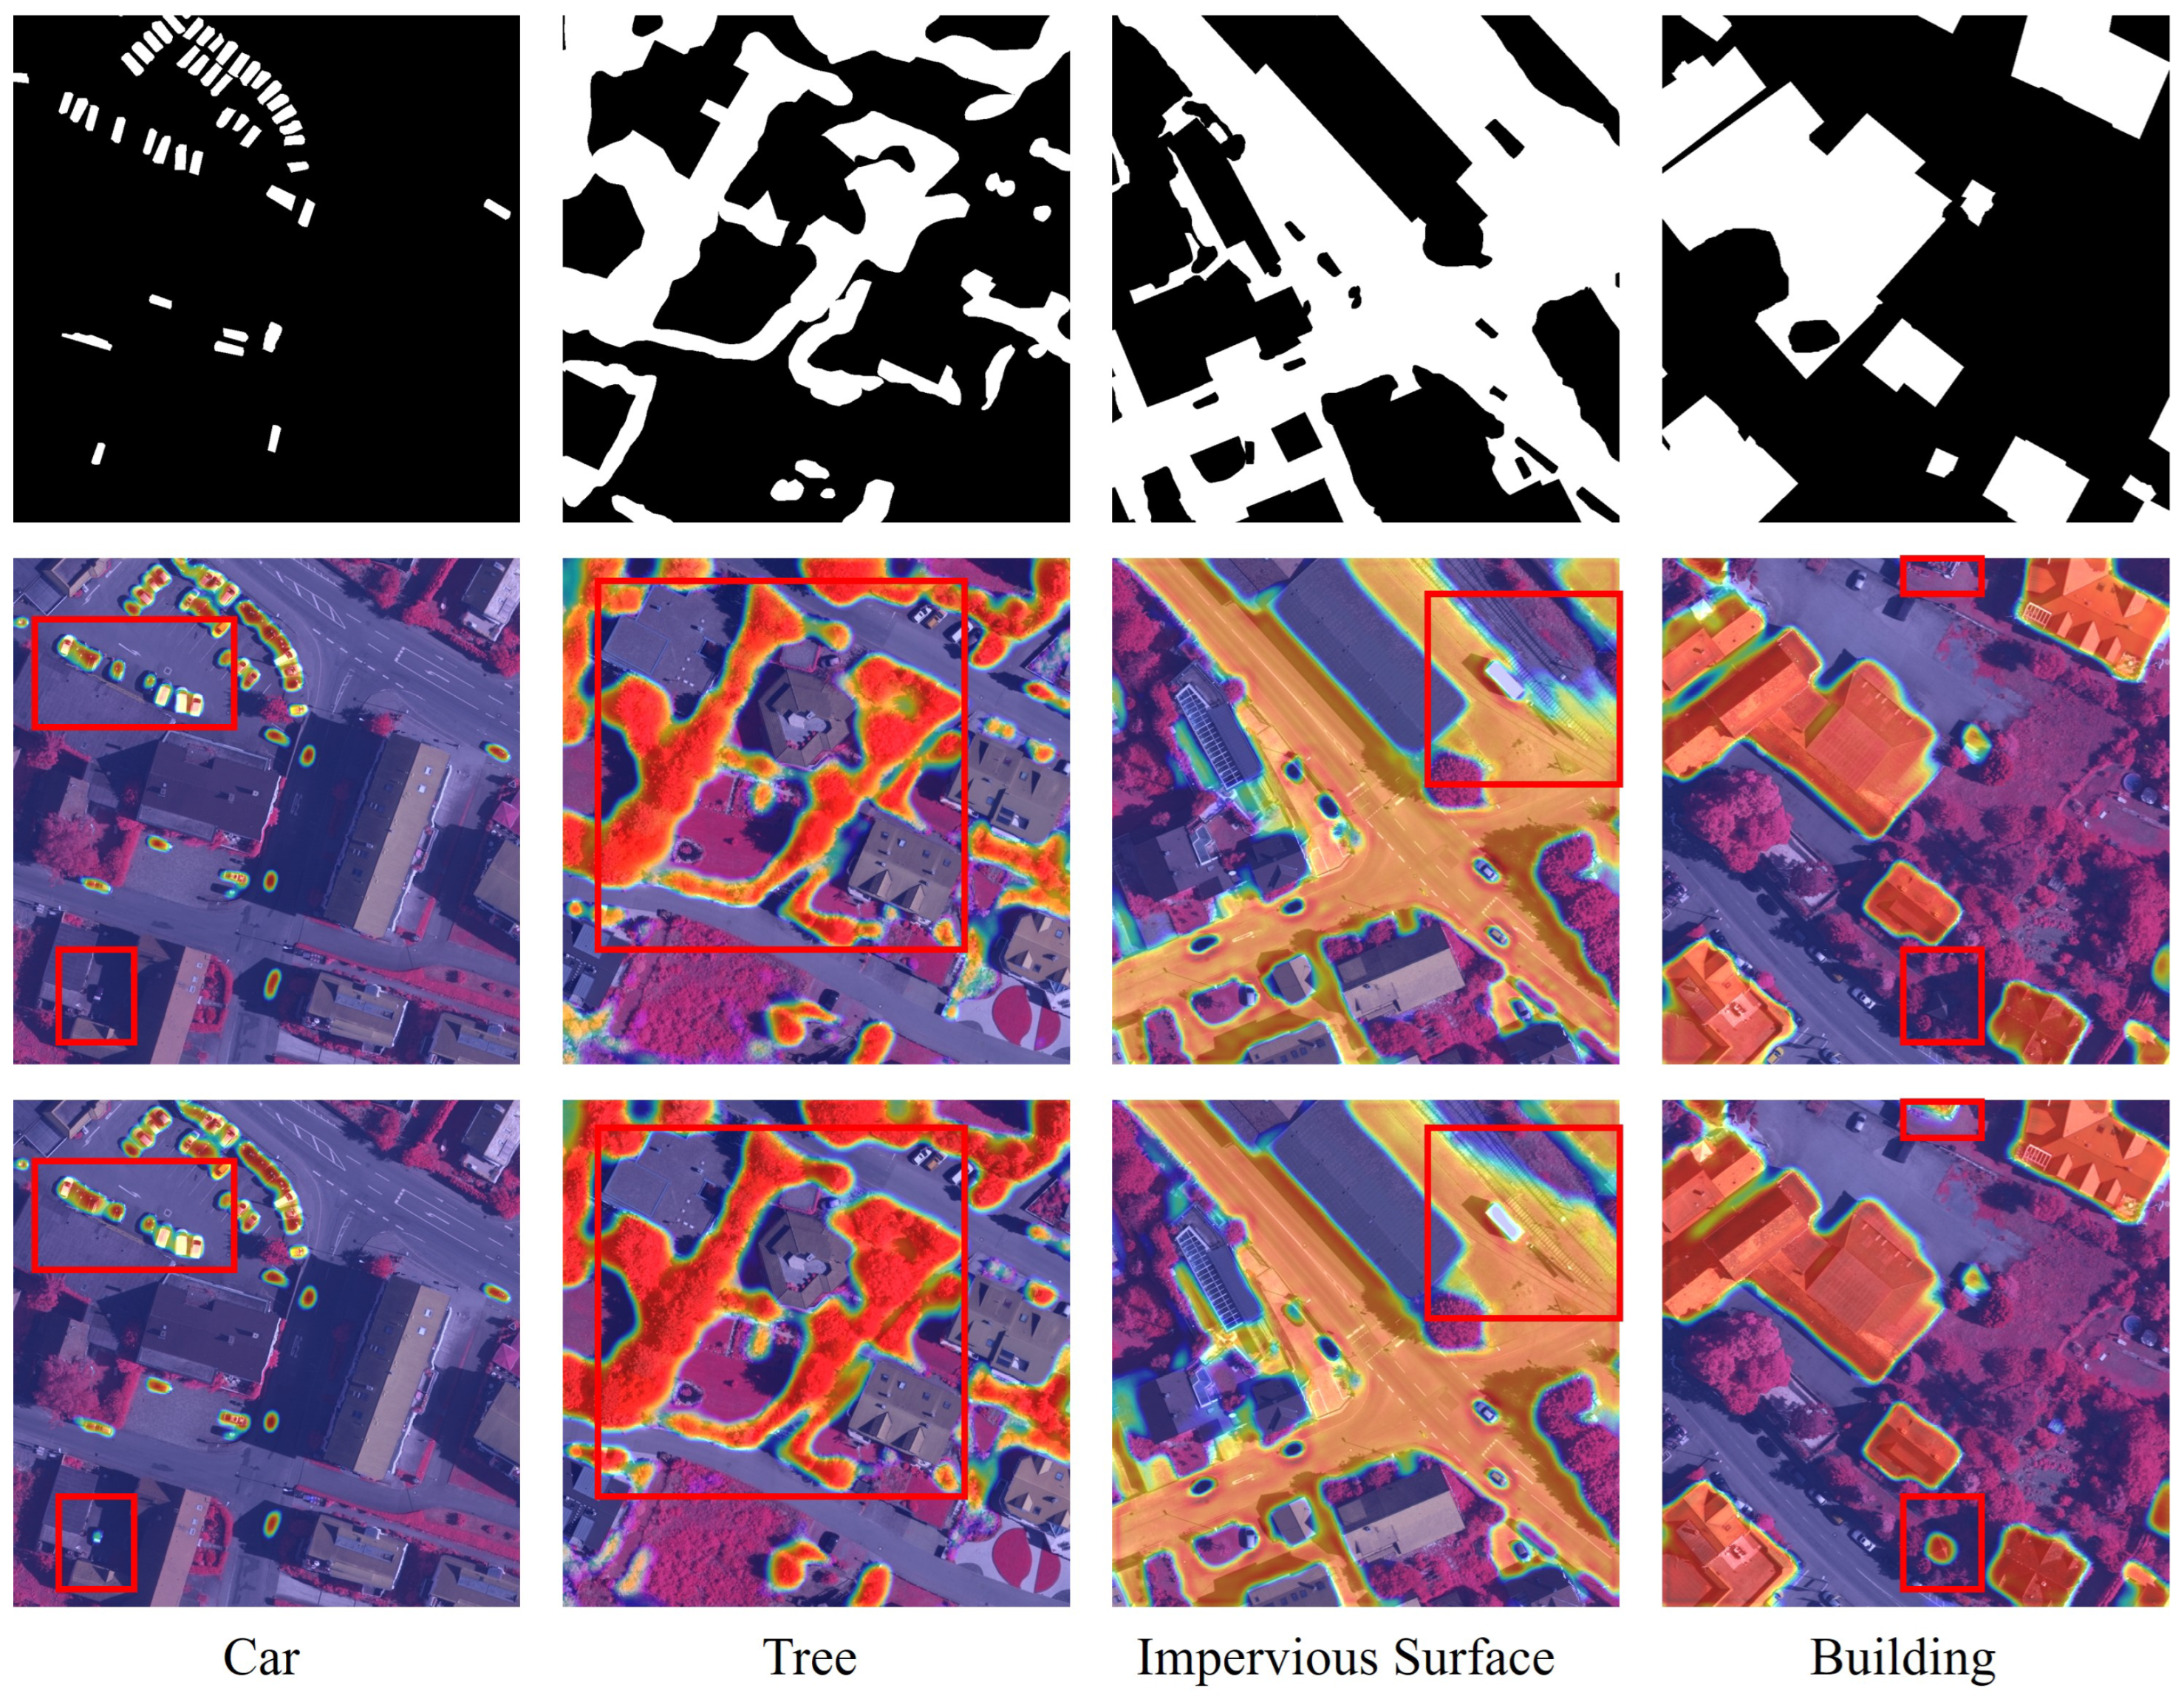
To further enhance the interpretability of the proposed Lite-BSSNet, we visualize the outputs of the Structural Blueprint Generator (SBG). Figure 10 presents the Grad-CAM++ [63] heatmaps corresponding to SBG. When the high-level feature extractor is implemented using a standard MLP (second row), the activations are relatively diffuse and often fail to delineate structure-sensitive regions, leading to inaccurate localization of elongated or boundary-dominant areas such as roads and tree contours. In contrast, after introducing the KAN-based SBG (third row), the activation maps exhibit clearer structural responses, and the highlighted regions become more aligned with the ground truth (first row), especially along class-transition boundaries and thin structures.
Figure 10.
Heatmaps of features output by KAN and MLP on the ISPRS Vaihingen test dataset, where the first row is the ground truth, the second row is the heatmap after MLP processing, and the third row is the heatmap after KAN processing. The red bounding boxes highlight representative regions for visual comparison.
To further evaluate the effectiveness of integrating KAN into SBG, we replaced the MLP in SBG with KAN while keeping all other components unchanged and measured boundary quality using the bF1 score. As shown in Table 8, the KAN variant achieved higher bF1 scores in all categories, indicating enhanced boundary delineation capabilities in the model’s output layer. Combined with the visualizations from Grad-CAM++ in Figure 10, these quantitative improvements align with qualitative observations, demonstrating that KAN promotes more discernible cross-channel interactions. This generates structurally enhanced blueprints that better preserve structural continuity.
Table 8.
Experimental results of the Structural Blueprint Generator (SBG) instantiated with KAN and a conventional MLP on the ISPRS Vaihingen dataset; the best result is shown in bold.
- (6)
- Topology-Consistency Evaluation of SRB
To verify the effectiveness of the proposed Structural Repair Block (SRB), we conduct an ablation study on SRB. Specifically, we construct two comparative variants: (1) w/o SRB, where SRB is removed from the end of the decoder and only the original upsampling and multi-scale fusion structure is retained; (2) w/SRB, where SRB is inserted at the same position to perform structured refinement and repair on high-resolution features.
Quantitative results are summarized in Table 9. Compared with w/o SRB, adding SRB yields consistent gains, with larger improvements on categories prone to interpolation smoothing and fusion noise. The overall topology-consistency metric mclDice also increases from 75.9% to 76.6% (+0.7%), indicating improved connectivity and structural integrity of thin structures.
Table 9.
Ablation of SRB on the ISPRS Vaihingen test dataset. clDice and its topology-aware decomposition (tPrec/tRec) are reported. denotes (w/SRB − w/o SRB). Bold values indicate performance improvements, and the improvement magnitude equals the bold number itself.
To clarify the source of this improvement, we report the clDice decomposition terms tPrec and tRec. SRB notably increases tPrec on structure-sensitive classes (Building +1.3%, LowVeg +4.6%, Car +3.2%), suggesting fewer spurious or misaligned centerlines near boundaries. It also improves tRec on ImSurf and Tree (+2.3% and +4.6%), implying its ability to effectively suppress unreliable responses near the boundary. Although tRec decreases on LowVeg (−5.1%), the overall gain in tPrec still results in improved clDice and IoU. These results align with SRB’s design: large-kernel attention provides long-range structural context, while spatial/channel gating suppresses unreliable boundary responses, jointly reducing topology drift and fragmentation.
5. Discussion
This section further analyzes the experimental results to better understand the advantages and limitations of the proposed Lite-BSSNet. We focus on the “blueprint–bridge–repair” decoding paradigm and discuss its effectiveness from three perspectives: performance on urban benchmark datasets, structural consistency, and computational efficiency. Specifically, we first analyze the segmentation performance and generalization behavior of Lite-BSSNet on different urban remote sensing benchmarks; then, based on a series of ablation studies, we examine the effectiveness of the three core components; finally, we summarize the trade-off between accuracy and efficiency and discuss limitations and future directions.
5.1. Performance on Remote Sensing Benchmarks
The experimental results show that Lite-BSSNet achieves high segmentation accuracy while maintaining a lightweight architectural design. The model obtains competitive mIoU and mF1 scores on both the ISPRS Vaihingen and Potsdam datasets, indicating stable performance trends across scenes with different spatial resolutions, object scales, and texture distributions. Specifically, Lite-BSSNet achieves 83.9% mIoU on the Vaihingen dataset and 86.7% mIoU on the Potsdam dataset while keeping the parameter scale and computational cost at a relatively low level.
Qualitative visualizations further verify the generalization ability of Lite-BSSNet. As shown in Figure 6 and Figure 7, in complex scenes such as dense building areas and narrow roads, Lite-BSSNet produces clearer boundaries and more continuous predictions and preserves more details in slender structures and complex contours.
5.2. Effectiveness of the Blueprint–Bridge–Repair Pipeline
Ablation studies validate the effectiveness of the three-stage decoding pipeline: enabling any single component (SBG, VSS-Bridge, or SRB) brings consistent gains while enabling all three achieves the best results on both datasets.
Among the three components, VSS-Bridge provides the most prominent standalone improvement: when enabled alone, it increases mIoU by 1.0% on the Vaihingen dataset and by 0.4% on the Potsdam dataset. This indicates that explicit cross-layer alignment before state space decoding is critical. Without this process, heterogeneous features from different encoder stages can introduce redundancy and semantic inconsistency, which may affect the stability of subsequent sequence modeling. Moreover, Table 6 shows that VSS-Bridge achieves the lowest ratios on the scanability metrics (TV, Scan, and Peak). This indicates that it better suppresses both average and worst-case token-to-token variations along the scan order. As a result, the features better match the streaming characteristics of visual state space models.
SBG provides structural constraints for decoding by generating a stable, edge-enhanced structural prior. The ablation results show that introducing SBG yields consistent performance improvements. In addition, interpretability analysis further supports its structural awareness: Grad-CAM++ visualizations show that the KAN-based SBG activations are more focused on structural boundary regions; boundary quality evaluation also shows that SBG-KAN improves the overall mbF1 and brings a slight mIoU gain. These results suggest that SBG helps suppress texture noise interference and enhances boundary-related responses, thereby improving the representation quality of structural details.
SRB is designed to alleviate boundary blurring and structural distortions introduced by interpolation-based upsampling and multi-scale fusion, thereby improving the structural quality of high-resolution outputs. The ablation results indicate that introducing SRB brings consistent gains on both datasets: on Vaihingen, mIoU increases from 82.1% to 82.9%, and on Potsdam, from 84.9% to 85.2%, showing a positive contribution to the final prediction. Further topology consistency evaluation shows that adding SRB increases the overall mclDice from 75.9% to 76.6%, with relatively clear improvements in structural connectivity for structure-sensitive categories such as buildings, low vegetation, and cars. Meanwhile, receptive field configuration experiments show that a moderate effective large receptive field achieves the best balance between performance and overhead: when the effective receptive field continues to increase, performance gains tend to saturate, while computational cost rises. These results are consistent with the design goal of SRB, namely, to provide richer structural context through large-receptive-field modeling and to suppress unreliable responses via spatial/channel gating, thereby mitigating structure breaks and noise accumulation caused by upsampling.
5.3. Balance Between Accuracy and Efficiency
From a deployment perspective, Lite-BSSNet achieves a good balance between segmentation accuracy and computational efficiency. On the Vaihingen dataset, the model achieves the highest mIoU among lightweight networks while maintaining low FLOPs. Compared with single-architecture decoders, the hybrid blueprint–bridge–repair decoding paradigm improves mIoU by approximately 1.2% without significantly increasing computational burden. This indicates that, compared with simply increasing model capacity or stacking heavier attention modules, restructuring the decoding process in a structured manner can improve performance more efficiently.
Therefore, Lite-BSSNet shows potential for practical remote sensing applications under resource-constrained conditions, such as UAV mapping, urban monitoring, and near-real-time semantic analysis in typical remote sensing task scenarios.
5.4. Limitations and Future Perspectives
Although Lite-BSSNet achieves certain performance improvements, it still has limitations. First, the current implementation does not fully realize the potential inference speed: the selective state mechanism in the visual state space module involves dynamic parameter updates, which may limit frame rate under real-time requirements. Future work could further improve runtime efficiency through state space execution optimization and hardware-aware acceleration.
Second, although the framework performs well on urban remote sensing benchmarks, its effectiveness on non-urban scenes or datasets with substantially different target morphologies remains to be verified. Future work may focus on extending the blueprint–bridge–repair paradigm to broader Mamba architectures, enhancing the interpretability of interactions among the three stages, and improving adaptability to diverse sensing modalities and complex environmental conditions.
6. Conclusions
The proposed framework follows an encoder–decoder architecture. The encoder extracts hierarchical features, and the decoder consists of three components: SBG, VSS-Bridge, and SRB. SBG transforms high-level features into an edge-enhanced structural blueprint that provides a global topological prior. VSS-Bridge aligns and filters multi-scale cross-layer features and projects them into a linear-complexity visual state space, enabling efficient long-range modeling. SRB restores thin structures via large-receptive-field modeling and spatial–channel gating, which reduces upsampling-induced distortions and improves geometric continuity. Extensive experiments on the ISPRS Vaihingen and Potsdam datasets, together with comprehensive ablation studies, demonstrate that Lite-BSSNet achieves state-of-the-art performance among lightweight CNN-, Transformer-, Mamba-, and hybrid-based models. The results confirm that Lite-BSSNet provides a favorable balance between segmentation accuracy, structural consistency, and computational efficiency.
Although Lite-BSSNet exhibits strong performance, future work may focus on improving the interpretability of interactions within the blueprint–bridge–repair decoding pipeline, extending the state space bridging mechanism to broader Mamba-based architectures, and enhancing the model’s adaptability to diverse remote sensing conditions and sensor modalities.
Author Contributions
Conceptualization, J.Y.; methodology, J.Y.; software, Y.C.; validation, J.Y.; formal analysis, J.Y.; investigation, J.Y. and Y.X.; resources, J.Y.; data curation, Y.C.; writing—original draft preparation, J.Y.; writing—review and editing, J.Y., Y.X., Y.C., Y.G. and W.L.; visualization, J.Y.; supervision, Y.X., Y.G. and W.L.; funding acquisition, Y.X. All authors have read and agreed to the published version of the manuscript.
Funding
This work was supported by the General Program of National Natural Science Foundation of China (Grant No. 72571281); the Hunan Excellent Young Scientists Fund (Grant No. 2025JJ40066); training Program for Excellent Young Innovators of Changsha (Grant No. kq2209001); the Fund of the National Key Laboratory of Space Target Awareness, and the Fund of Laboratory for Big Data and Decision.
Data Availability Statement
The code will be released at https://github.com/hm-hm53/Lite-BSSNet (accessed on 26 January 2026).
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Ding, H.; Xia, B.; Liu, W.; Zhang, Z.; Zhang, J.; Wang, X.; Xu, S. A Novel Mamba Architecture with a Semantic Transformer for Efficient Real-Time Remote Sensing Semantic Segmentation. Remote Sens. 2024, 16, 2620. [Google Scholar] [CrossRef] [Scilit]
- Chen, Y.; Zhang, S.; Han, T.; Du, Y.; Zhang, W.; Li, J. Chat3D: Interactive understanding 3D scene-level point clouds by chatting with foundation model for urban ecological construction. ISPRS J. Photogramm. Remote Sens. 2024, 212, 181–192. [Google Scholar] [CrossRef] [Scilit]
- Yang, H.; Jiang, Z.; Zhang, Y.; Wu, Y.; Luo, H.; Zhang, P.; Wang, B. A high-resolution remote sensing land use/land cover classification method based on multi-level features adaptation of segment anything model. Int. J. Appl. Earth Obs. Geoinf. 2025, 141, 104659. [Google Scholar] [CrossRef] [Scilit]
- Wang, H.; Dai, Y.; Yao, Q.; Ma, L.; Zhang, Z.; Lv, X. Multi-task learning model driven by climate and remote sensing data collaboration for mid-season cotton yield prediction. Field Crop. Res. 2025, 333, 110070. [Google Scholar] [CrossRef] [Scilit]
- Li, Y.; Fu, K.; Sun, H.; Sun, X. An Aircraft Detection Framework Based on Reinforcement Learning and Convolutional Neural Networks in Remote Sensing Images. Remote Sens. 2018, 10, 243. [Google Scholar] [CrossRef] [Scilit]
- Long, J.; Shelhamer, E.; Darrell, T. Fully convolutional networks for semantic segmentation. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Boston, MA, USA, 7–12 June 2015; pp. 3431–3440. [Google Scholar]
- Ronneberger, O.; Fischer, P.; Brox, T. U-net: Convolutional networks for biomedical image segmentation. In Medical Image Computing and Computer-Assisted Intervention–MICCAI 2015; Springer: Cham, Switzerland, 2015; pp. 234–241. [Google Scholar]
- Gao, L.; Liu, H.; Yang, M.; Chen, L.; Wan, Y.; Xiao, Z.; Qian, Y. STransFuse: Fusing Swin Transformer and Convolutional Neural Network for Remote Sensing Image Semantic Segmentation. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2021, 14, 10990–11003. [Google Scholar] [CrossRef] [Scilit]
- Wang, L.; Li, R.; Zhang, C.; Fang, S.; Duan, C.; Meng, X.; Atkinson, P.M. UNetFormer: A UNet-like transformer for efficient semantic segmentation of remote sensing urban scene imagery. ISPRS J. Photogramm. Remote Sens. 2022, 190, 196–214. [Google Scholar] [CrossRef] [Scilit]
- Wu, H.; Zhang, M.; Huang, P.; Tang, W. CMLFormer: CNN and Multiscale Local-Context Transformer Network for Remote Sensing Images Semantic Segmentation. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2024, 17, 7233–7241. [Google Scholar] [CrossRef] [Scilit]
- Bao, M.; Lyu, S.; Xu, Z.; Zhou, H.; Ren, J.; Xiang, S.; Li, X.; Cheng, G. Vision Mamba in Remote Sensing: A Comprehensive Survey of Techniques, Applications and Outlook. arXiv 2025, arXiv:2505.00630. [Google Scholar] [CrossRef] [Scilit]
- Liu, Z.; Mao, H.; Wu, C.-Y.; Feichtenhofer, C.; Darrell, T.; Xie, S. A ConvNet for the 2020s. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, LA, USA, 18–24 June 2022; pp. 11966–11976. [Google Scholar]
- Li, Y.; Li, X.; Dai, Y.; Hou, Q.; Liu, L.; Liu, Y.; Cheng, M.M.; Yang, J. LSKNet: A Foundation Lightweight Backbone for Remote Sensing. Int. J. Comput. Vis. 2025, 133, 1410–1431. [Google Scholar] [CrossRef] [Scilit]
- Li, D.; Li, L.; Chen, Z.; Li, J. ShiftwiseConv: Small Convolutional Kernel with Large Kernel Effect. In Proceedings of the Computer Vision and Pattern Recognition Conference, Nashville, TN, USA, 11–15 June 2025; pp. 25281–25291. [Google Scholar]
- Dosovitskiy, A.; Beyer, L.; Kolesnikov, A.; Weissenborn, D.; Zhai, X.; Unterthiner, T.; Dehghani, M.; Minderer, M.; Heigold, G.; Gelly, S.; et al. An image is worth 16x16 words: Transformers for image recognition at scale. In Proceedings of the International Conference on Learning Representations, ICLR 2021, Vienna, Austria, 4 May 2021. [Google Scholar]
- Wang, W.; Xie, E.; Li, X.; Fan, D.P.; Song, K.; Liang, D.; Lu, T.; Luo, P.; Shao, L. Pyramid vision transformer: A versatile backbone for dense prediction without convolutions. In Proceedings of the IEEE/CVF International Conference on Computer Vision, Montreal, QC, Canada, 10–17 October 2021; pp. 568–578. [Google Scholar]
- Zhu, L.; Liao, B.; Zhang, Q.; Wang, X.; Liu, W.; Wang, X. Vision mamba: Efficient visual representation learning with bidirectional state space model. In Proceedings of the International Conference on Machine Learning, Vienna, Austria, 21–27 July 2024. [Google Scholar]
- Liu, Y.; Tian, Y.; Zhao, Y.; Yu, H.; Xie, L.; Wang, Y.; Ye, Q.; Jiao, J.; Liu, Y. VMamba: Visual State Space Model. Adv. Neural Inf. Process. Syst. 2024, 37, 103031–103063. [Google Scholar]
- Liu, M.; Dan, J.; Lu, Z.; Yu, Y.; Li, Y.; Li, X. CM-UNet: Hybrid CNN-Mamba UNet for Remote Sensing Image Semantic Segmentation. arXiv 2024, arXiv:2405.10530. [Google Scholar]
- Wang, Z.; Yi, J.; Chen, A.; Chen, L.; Lin, H.; Xu, K. Accurate semantic segmentation of very high-resolution remote sensing images considering feature state sequences: From benchmark datasets to urban applications. ISPRS J. Photogramm. Remote Sens. 2025, 220, 824–840. [Google Scholar] [CrossRef] [Scilit]
- Ma, X.; Zhang, X.; Pun, M.-O. RS3Mamba: Visual State Space Model for Remote Sensing Image Semantic Segmentation. IEEE Geosci. Remote Sens. Lett. 2024, 21, 6011405. [Google Scholar] [CrossRef] [Scilit]
- Zhu, E.; Chen, Z.; Wang, D.; Shi, H.; Liu, X.; Wang, L. UNetMamba: An Efficient UNet-Like Mamba for Semantic Segmentation of High-Resolution Remote Sensing Images. IEEE Geosci. Remote Sens. Lett. 2025, 22, 6001205. [Google Scholar] [CrossRef] [Scilit]
- Cao, Y.; Liu, C.; Wu, Z.; Zhang, L.; Yang, L. Remote Sensing Image Segmentation Using Vision Mamba and Multi-Scale Multi-Frequency Feature Fusion. Remote Sens. 2025, 17, 1390. [Google Scholar] [CrossRef] [Scilit]
- Lou, M.; Fu, Y.; Yu, Y. Sparx: A sparse cross-layer connection mechanism for hierarchical vision mamba and transformer networks. In Proceedings of the AAAI Conference on Artificial Intelligence; AAAI Press: Washington, DC, USA, 2025. [Google Scholar]
- Kass, M.; Witkin, A.; Terzopoulos, D. Snakes: Active contour models. Int. J. Comput. Vis. 1988, 1, 321–331. [Google Scholar] [CrossRef] [Scilit]
- Boykov, Y.Y.; Jolly, M.-P. Interactive graph cuts for optimal boundary & region segmentation of objects in N-D images. In Proceedings of the Eighth IEEE International Conference on Computer Vision, ICCV 2001, Vancouver, BC, Canada, 7–14 July 2001; pp. 105–112. [Google Scholar]
- Xie, S.; Tu, Z. Holistically-Nested Edge Detection. In Proceedings of the 2015 IEEE International Conference on Computer Vision, ICCV 2015, Santiago, Chile, 7–13 December 2015; pp. 1395–1403. [Google Scholar]
- You, X.; He, J.; Yang, J.; Gu, Y. Learning With Explicit Shape Priors for Medical Image Segmentation. IEEE Trans. Med Imaging 2025, 44, 927–940. [Google Scholar] [CrossRef] [Scilit]
- Radosavovic, I.; Kosaraju, R.P.; Girshick, R.; He, K.; Dollár, P. Designing Network Design Spaces. In Proceedings of the 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR 2020), Seattle, WA, USA, 14–19 June 2020; pp. 10425–10433. [Google Scholar]
- Guo, M.; Liu, H.; Xu, Y.; Huang, Y. Building Extraction Based on U-Net with an Attention Block and Multiple Losses. Remote Sens. 2020, 12, 1400. [Google Scholar] [CrossRef] [Scilit]
- Sharma, S.K.; Sharma, V.; Mishra, V. Building Extraction for Urban Infrastructure Mapping Using Deep Neural Networks and High-Resolution Remote Sensing Data. J. Indian Soc. Remote Sens. 2025, 53, 2223–2237. [Google Scholar] [CrossRef] [Scilit]
- Yang, J.; Liu, T.; Zhang, L.; Zhang, Y. Effective Road Segmentation With Selective State-Space Model and Frequency Feature Compensation. IEEE Trans. Geosci. Remote Sens. 2025, 63, 5603813. [Google Scholar] [CrossRef] [Scilit]
- Badrinarayanan, V.; Kendall, A.; Cipolla, R. SegNet: A Deep Convolutional Encoder-Decoder Architecture for Image Segmentation. IEEE Trans. Pattern Anal. Mach. Intell. 2017, 39, 2481–2495. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Sun, Y.; Tian, Y.; Xu, Y. Problems of encoder-decoder frameworks for high-resolution remote sensing image segmentation: Structural stereotype and insufficient learning. Neurocomputing 2019, 330, 297–304. [Google Scholar] [CrossRef] [Scilit]
- Teng, J.; Zhu, Z.; Pu, D.; Wang, T.; Zeng, X.; Snoussi, H.; Shi, R.; Sheng, Q.Z.; He, H.; Li, J. MSCSCNet: Multi-Scale Convolution Selective Context Network With Boundary Supervision for Semantic Segmentation of Remote Sensing Images. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2025, 18, 25892–25908. [Google Scholar] [CrossRef] [Scilit]
- Li, R.; Zheng, S.; Zhang, C.; Duan, C.; Wang, L.; Atkinson, P.M. ABCNet: Attentive bilateral contextual network for efficient semantic segmentation of Fine-Resolution remotely sensed imagery. ISPRS J. Photogramm. Remote Sens. 2021, 181, 84–98. [Google Scholar] [CrossRef] [Scilit]
- Fu, J.; Liu, J.; Tian, H.; Li, Y.; Bao, Y.; Fang, Z.; Lu, H. Dual Attention Network for Scene Segmentation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Long Beach, CA, USA, 15–20 June 2019; pp. 3141–3149. [Google Scholar]
- Chen, J.; Lu, Y.; Yu, Q.; Luo, X.; Adeli, E.; Wang, Y.; Lu, L.; Yuille, A.L.; Zhou, Y. TransUNet: Transformers Make Strong Encoders for Medical Image Segmentation. arXiv 2021, arXiv:2102.04306. [Google Scholar] [CrossRef] [Scilit]
- Ma, X.; Zhang, X.; Pun, M.-O.; Liu, M. A Multilevel Multimodal Fusion Transformer for Remote Sensing Semantic Segmentation. IEEE Trans. Geosci. Remote Sens. 2024, 62, 5403215. [Google Scholar] [CrossRef] [Scilit]
- Liu, Z.; Lin, Y.; Cao, Y.; Hu, H.; Wei, Y.; Zhang, Z.; Lin, S.; Guo, B. Swin Transformer: Hierarchical Vision Transformer using Shifted Windows. In Proceedings of the 2021 IEEE/CVF International Conference on Computer Vision (ICCV), Montreal, QC, Canada, 11–17 October 2021. [Google Scholar]
- He, X.; Zhou, Y.; Zhao, J.; Zhang, D.; Yao, R.; Xue, Y. Swin Transformer Embedding UNet for Remote Sensing Image Semantic Segmentation. IEEE Trans. Geosci. Remote Sens. 2022, 60, 4408715. [Google Scholar] [CrossRef] [Scilit]
- Huang, L.; Jiang, B.; Lv, S.; Liu, Y.; Fu, Y. Deep-Learning-Based Semantic Segmentation of Remote Sensing Images: A Survey. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2024, 17, 8370–8396. [Google Scholar] [CrossRef] [Scilit]
- Chen, H.; Luo, H.; Wang, C. AfaMamba: Adaptive Feature Aggregation With Visual State Space Model for Remote Sensing Images Semantic Segmentation. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2025, 18, 8965–8983. [Google Scholar] [CrossRef] [Scilit]
- Zhu, Q.; Cai, Y.; Fang, Y.; Yang, Y.; Chen, C.; Fan, L.; Nguyen, A. Samba: Semantic segmentation of remotely sensed images with state space model. Heliyon 2024, 10, e38495. [Google Scholar] [CrossRef] [Scilit]
- Zhao, S.; Chen, H.; Zhang, X.; Xiao, P.; Bai, L.; Ouyang, W. RS-Mamba for Large Remote Sensing Image Dense Prediction. IEEE Trans. Geosci. Remote Sens. 2024, 62, 5633314. [Google Scholar] [CrossRef] [Scilit]
- Li, L.; Yi, J.; Fan, H.; Lin, H. A Lightweight Semantic Segmentation Network Based on Self-Attention Mechanism and State Space Model for Efficient Urban Scene Segmentation. IEEE Trans. Geosci. Remote Sens. 2025, 63, 4703215. [Google Scholar] [CrossRef] [Scilit]
- Chu, X.; Tian, Z.; Zhang, B.; Wang, X.; Shen, C. Conditional Positional Encodings for Vision Transformers. In Proceedings of the 10th International Conference on Learning Representations (ICLR 2022), Online, 25–29 April 2022. [Google Scholar]
- Cao, J.; Li, Y.; Sun, M.; Chen, Y.; Lischinski, D.; Cohen-Or, D.; Chen, B.; Tu, C. DO-Conv: Depthwise Over-Parameterized Convolutional Layer. IEEE Trans. Image Process. 2022, 31, 3726–3736. [Google Scholar] [CrossRef] [Scilit]
- Liu, Z.; Wang, Y.; Vaidya, S.; Ruehle, F.; Halverson, J.; Soljacic, M.; Hou, T.Y.; Tegmark, M. KAN: Kolmogorov–Arnold Networks. In Proceedings of the Thirteenth International Conference on Learning Representations, ICLR 2025, Singapore, 24–28 April 2025. [Google Scholar]
- Li, C.; Liu, X.; Li, W.; Wang, C.; Liu, H.; Liu, Y.; Chen, Z.; Yuan, Y. U-kan makes strong backbone for medical image segmentation and generation. In Proceedings of the AAAI Conference on Artificial Intelligence, Philadelphia, PA, USA, 25 February–4 March 2025. [Google Scholar]
- Zhang, S.; Liu, J.; Qian, T.; Li, X. Prompt-Guided Dual-Path UNet with Mamba for Medical Image Segmentation. arXiv 2025, arXiv:2503.19589. [Google Scholar]
- Zhang, Y. KM-UNet: KAN Mamba UNet for Medical Image Segmentation. arXiv 2025, arXiv:2501.02559. [Google Scholar]
- Shit, S.; Paetzold, J.C.; Sekuboyina, A.; Ezhov, I.; Unger, A.; Zhylka, A.; Pluim, J.P.; Bauer, U.; Menze, B.H. clDice-A Novel Topology-Preserving Loss Function for Tubular Structure Segmentation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Nashville, TN, USA, 20–25 June 2021; pp. 16555–16564. [Google Scholar]
- Oršić, M.; Šegvić, S. Efficient semantic segmentation with pyramidal fusion. Pattern Recognit. 2021, 110, 107611. [Google Scholar] [CrossRef] [Scilit]
- Fan, X.; Zhou, W.; Qian, X.; Yan, W. Progressive Adjacent-Layer coordination symmetric cascade network for semantic segmentation of Multimodal remote sensing images. Expert Syst. Appl. 2024, 238, 121999. [Google Scholar] [CrossRef] [Scilit]
- Strudel, R.; Garcia, R.; Laptev, I.; Schmid, C. Segmenter: Transformer for Semantic Segmentation. In Proceedings of the 2021 IEEE/CVF International Conference on Computer Vision (ICCV), Montreal, QC, Canada, 11–17 October 2021; pp. 7242–7252. [Google Scholar]
- Wang, L.; Li, R.; Wang, D.; Duan, C.; Wang, T.; Meng, X. Transformer Meets Convolution: A Bilateral Awareness Network for Semantic Segmentation of Very Fine Resolution Urban Scene Images. Remote Sens. 2021, 13, 3065. [Google Scholar] [CrossRef] [Scilit]
- Zhou, H.; Xiao, X.; Li, H.; Liu, X.; Liang, P. Hybrid shunted transformer embedding unet for remote sensing image semantic segmentation. Neural Comput. Appl. 2024, 36, 15705–15720. [Google Scholar] [CrossRef] [Scilit]
- Mu, J.; Zhou, S.; Sun, X. PPMamba: Enhancing Semantic Segmentation in Remote Sensing Imagery by SS2D. IEEE Geosci. Remote Sens. Lett. 2025, 22, 6001705. [Google Scholar] [CrossRef] [Scilit]
- Wang, L.; Li, D.; Dong, S.; Meng, X.; Zhang, X.; Hong, D. PyramidMamba: Rethinking pyramid feature fusion with selective space state model for semantic segmentation of remote sensing imagery. Int. J. Appl. Earth Obs. Geoinf. 2025, 144, 104884. [Google Scholar] [CrossRef] [Scilit]
- Cao, H.; Wang, Y.; Chen, J.; Jiang, D.; Zhang, X.; Tian, Q.; Wang, M. Swin-Unet: Unet-Like Pure Transformer for Medical Image Segmentation. In Proceedings of the Computer Vision–ECCV 2022 Workshops, Tel Aviv, Israel, 23–27 October 2022; pp. 205–218. [Google Scholar]
- Wan, Q.; Huang, Z.; Lu, J.; Yu, G.; Zhang, L. SeaFormer: Squeeze-enhanced Axial Transformer for Mobile Semantic Segmentation. In Proceedings of the Eleventh International Conference on Learning Representations, ICLR 2023, Kigali, Rwanda, 1–5 May 2023. [Google Scholar]
- Chattopadhay, A.; Sarkar, A.; Howlader, P.; Balasubramanian, V.N. Grad-CAM++: Generalized Gradient-Based Visual Explanations for Deep Convolutional Networks. In Proceedings of the 2018 IEEE Winter Conference on Applications of Computer (WACV), Lake Tahoe, NV, USA, 12–15 March 2018. [Google Scholar]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.