


Abstract
Understanding high-dimensional dependencies in modern financial systems requires time series models that capture both contemporaneous and dynamic linkages. This study develops a sparse spatio-temporal vector autoregressive framework to analyse the network structure of the Korean won exchange rate against 36 major trading-partner currencies. The model combines the generalised Yule–Walker equations with structured penalisation to jointly estimate instantaneous and lagged interactions in a data-driven manner. This approach allows for the recovery of economically meaningful spillover networks while maintaining tractability in high dimensions. Using daily data from 2019 to 2023, the results reveal pronounced contemporaneous spillovers among currencies closely tied to Korea’s trade and financial networks, notably the U.S. dollar, Chinese yuan, Japanese yen, and key ASEAN currencies. Monte Carlo simulations confirm the estimator’s consistency and convergence properties, while empirical forecasting exercises demonstrate systematic improvements in both mean-squared and robust error metrics relative to benchmark VAR and spatial autoregressive models. The evidence highlights that modelling sparse, high-dimensional time series structures enhances predictive accuracy and interpretability, particularly under nonstationary and heterogeneous conditions. The proposed framework provides a flexible tool for exploring interconnected time series in economics and finance, offering new insights into exchange-rate linkages and risk transmission in globally integrated markets.
Keywords:
high-dimensional time series; sparse spatio-temporal modelling; vector autoregression; exchange rate networks; forecasting and risk transmission MSC:
15B48; 40B05; 91B84
1. Introduction
The Korean won (KRW) occupies a pivotal position in Asia’s foreign exchange markets, reflecting the country’s deep integration into global production networks, capital markets, and cross-border financial linkages (Taly [1]; Kim et al. [2]; Plantin and Shin [3]). As one of the most open and trade-dependent economies worldwide, Korea faces substantial exposure to currency fluctuations stemming from its major partners, including the United States, China, Japan, and the euro area, as well as an expanding group of emerging economies (Lee and Kim [4]; Son et al. [5]). These interconnections generate bilateral exchange-rate co-movements that are both contemporaneous and asymmetric, often forming clusters of volatility and spillover effects that conventional low-dimensional econometric models fail to represent adequately. Such dynamics mirror broader patterns observed in global asset and currency markets, where information diffusion and risk transmission follow complex, network-like structures (Kirkulak Uludag, and Khurshid [6]; Chen et al. [7]). Understanding these high-dimensional interdependencies has become increasingly essential for assessing external vulnerabilities, refining exchange-rate forecasts, and designing macro-financial policies in a rapidly evolving global environment (Fernández-Rodríguez and Sosvilla-Rivero [8]; Wang et al. [9]; Boakye et al. [10]).
Traditional approaches to modelling exchange-rate behaviour—such as vector autoregressions (VAR), factor models, or structural formulations rooted in macroeconomic theory—have significantly advanced empirical understanding but remain limited in scope. These models often impose restrictive assumptions on the dimensionality of information sets or rely on predefined interaction structures across currencies (Chan and Eisenstat [11]; Huber and Feldkircher [12]). In contrast, modern foreign-exchange systems are shaped by dense information flows, nonstationary interdependencies, and heterogeneous responses to global shocks (Barigozzi and Hallin [13]; Barigozzi and Brownlees [14]). Bilateral rates associated with the KRW, in particular, exhibit simultaneous adjustments driven by shared macroeconomic forces, order-flow dynamics, and regionally concentrated financial integration (Krohn and Sushko [15]; Cespa et al. [16]). These attributes underscore the need for analytical frameworks that can capture both instantaneous and dynamic dependencies within a scalable, data-driven structure capable of revealing sparse yet economically interpretable patterns (Chen et al. [17]).
Recent advances in high-dimensional econometrics and sparse time-series estimation have greatly expanded the empirical toolbox for analysing complex financial systems. Within this literature, sparse VAR models have become a dominant approach, yet most existing formulations concentrate on lagged dependence in reduced-form representations, treating contemporaneous interactions implicitly or relegating them to the innovation structure. Network-based methods address this limitation by emphasising cross-sectional linkages, but they typically rely on pre-specified weight matrices or externally imposed topologies, which constrain the data’s ability to reveal evolving interaction patterns. Against this background, the sparse spatio-temporal vector autoregressive model (SPLASH) provides a distinct methodological alternative that bridges these strands (Ahelegbey and Giudici [18]; Boakye et al. [10]; Gaskin et al. [19]). By embedding structured sparsity directly into a spatio-temporal VAR with explicit contemporaneous dependence, the framework allows instantaneous and dynamic spillovers to be estimated jointly within a unified system. This design avoids reliance on predetermined network configurations, while preserving interpretability through economically motivated sparsity patterns. Such features are particularly relevant for exchange-rate dynamics, where rapid information transmission and simultaneous adjustments coexist with persistent propagation mechanisms (Bräuning and Sheremirov [20]; Camara et al. [21]). The present study applies this framework to a high-dimensional panel of 36 bilateral KRW exchange rates covering Korea’s key trading partners and major financial counterparts from 2019 to 2023. This setting captures the breadth of Korea’s international exposure and offers a rich environment for examining exchange-rate connectedness (Hung [22]; Guru and Yadav [23]). By estimating a spatio-temporal VAR with structured sparsity, the analysis identifies the underlying network of inter-currency relationships, quantifies the direction and intensity of spillovers, and evaluates how this approach improves forecasting performance relative to traditional specifications (Shen et al. [24]; Ullah and Huang [25]). This methodological design is closely aligned with recent advances in nonlinear and complex time-series analysis, which emphasise integrating flexible dependence structures with modern regularisation to model interconnected systems [26,27].
Viewed through this lens, the proposed framework can be seen as a synthesis of recent developments in nonlinear time-series analysis and high-dimensional network modelling, tailored to the empirical features of modern financial systems. To clarify the scope of the analysis, the primary objective of this study is structural rather than predictive. The VAR-based framework inspired by the SPLASH conceptual structure is employed first to recover contemporaneous interdependencies, identify channels of shock transmission, and characterise the network architecture of high-dimensional exchange-rate systems. These structural features form the core contribution of the paper and provide economic insight into how exchange-rate movements propagate across currencies. Forecasting is introduced as a separate and complementary module. Its purpose is not to redefine the methodological focus, but to assess whether the recovered network structure carries empirical relevance in out-of-sample settings. In this sense, improvements in forecasting performance are interpreted as validation of the structural model, rather than as the primary goal of the analysis. In this study, the notion of “channels of influence” is understood in a reduced-form yet economically interpretable sense. Exchange-rate interactions reflect the joint operation of several underlying mechanisms, including price adjustment and valuation effects, liquidity and trading-activity transmission, global risk sentiment, and policy-driven macro-financial shocks. Rather than isolating each channel through separate observed proxies, the framework is designed to recover their combined impact endogenously through contemporaneous and dynamic cross-currency dependence. This approach allows the data to determine how different transmission mechanisms interact within a high-dimensional exchange-rate system, without imposing restrictive assumptions on which channel dominates ex ante.
The contribution of this research is primarily methodological. The proposed framework introduces a sparse spatio-temporal VAR that jointly models contemporaneous and dynamic interactions in high-dimensional systems, a feature that is absent from standard sparse VAR formulations. By combining generalised Yule–Walker estimation with diagonally structured regularisation, the approach accommodates instantaneous spillovers while remaining tractable in large dimensions. This structure enables a fine-grained representation of exchange-rate dynamics that cannot be achieved through reduced-form or purely lag-based specifications. A second contribution concerns network identification. Unlike existing network-based models that impose interaction structures ex ante, the proposed method recovers exchange-rate networks endogenously from the data. As a result, economically meaningful dependence patterns emerge without reliance on fixed spatial or trade-based weights. Applied to bilateral exchange rates, this framework provides one of the earliest sparse spatio-temporal VAR analyses of currency networks, allowing contemporaneous and lagged interactions to be examined jointly across a broad set of exchange rates (Habib et al. [28]; Gil-Alana and Carcel [29]). The empirical results reveal interpretable structures dominated by the U.S. dollar, Chinese yuan, Japanese yen, and key ASEAN currencies, highlighting the regional and global channels through which shocks propagate in the Korean foreign-exchange market (Le et al. [30]). Finally, the framework is supported by new theoretical results that establish finite-sample and asymptotic guarantees under contemporaneous dependence, providing a rigorous foundation for empirical analysis in high-dimensional exchange-rate systems. These methodological advances translate into tangible empirical gains. Using a rolling-window forecasting design, the analysis shows that SPLASH consistently outperforms spatial-temporal autoregressive, banded VAR, and penalised VAR benchmarks under both mean-squared and robust prediction metrics (Hauzenberger and Huber [31]). Taken together, these contributions underscore the value of integrating structured sparsity with spatio-temporal modelling to better capture the structure, stability, and predictive behaviour of Korea’s exchange-rate system in an increasingly interconnected financial environment.
2. The High-Dimensional Vector Autoregressive Framework
Before establishing the theoretical framework, all the preliminaries used in this are shown in Supplementary Materials. Consistent with scholars (Dou et al. [32]; Hou et al. [33]; Pu et al. [34]), a spatio-temporal vector autoregressive representation is adopted and expressed as
where collects, at time , the observations associated with exchange-rate nodes linked to the KRW. The matrix , subject to the restriction for , characterises contemporaneous cross-currency interactions within the KRW-centred exchange-rate system. Dynamic intertemporal dependence is captured by the matrix , which relates current exchange-rate movements to their lagged counterparts. The innovation vector represents idiosyncratic shocks and unanticipated fluctuations affecting the exchange-rate network. Specification (1) is well-suited to modelling high-dimensional exchange-rate dynamics in globally integrated currency markets. In the present context, each element of corresponds to the return or change of a bilateral exchange rate between the KRW and a major foreign currency. The contemporaneous component captures instantaneous spillovers across currencies arising from common risk factors, financial market linkages, or synchronised trading behaviour, while the lagged term reflects the propagation of past exchange-rate movements over time. In economic terms, these instantaneous interactions summarise fast-moving transmission channels such as price discovery, liquidity conditions, and shifts in global risk sentiment, while the lagged structure reflects slower propagation associated with adjustment frictions and delayed policy or macro-financial effects. As commonly observed in foreign-exchange markets, such interactions tend to exhibit localised dependence in an economic sense, whereby exchange-rate nodes that are closely connected through trade exposure, financial integration, or regional linkages exert stronger mutual influence. This structured cross-currency dependence is discussed further in Section 2.2, where the notation and theoretical foundations of the subsequent analysis are derived from model (1). Section 3.3 broadens the framework by incorporating exogenous variables. In the exchange-rate context, this refinement allows a more direct representation of additional determinants of KRW dynamics beyond endogenous cross-currency effects, such as global financial requirements, policy-driven shocks, and external macroeconomic influences. In empirical implementation, the vector does not consist of exchange-rate levels. Instead, each component represents the daily return or log-difference of a bilateral KRW exchange rate. This transformation is applied prior to estimation in order to mitigate non-stationary behaviour commonly observed in exchange-rate levels and to ensure that the dynamic system is defined on a stable scale. Working with returns allows the contemporaneous and lagged interaction structure to be interpreted as transmission mechanisms governing short-horizon exchange-rate adjustments rather than long-run trend movements.
2.1. Dynamic Stability and Cross-Currency Interdependence
To guarantee that the proposed spatio-temporal VAR specification produces a coherent dynamic evolution and preserves stability when characterising exchange-rate interdependencies, the set of permissible parameter values is restricted in the manner described below.
Condition 1.
It is required that
and and . Condition 1 guarantees that the specification can be expressed in a dynamically stable reduced-form VAR(1) structure. This conclusion is derived from two fundamental aspects. To begin with, this requirement constrains the overall magnitude of the contemporaneous interaction matrix by restricting its largest aggregated row and column effects, thus moderating instantaneous cross-currency linkages within the KRW-based exchange-rate network. Invertibility of is kept, because of . Thereinto, the reduced-form representation can be written as
In Equation (2), ; shows that the total magnitudes across columns and rows of are bounded by a constant across all dimensions. This requirement represents the exchange-rate network analogue of Condition B in Giordano et al. [35] and Feo et al. [36]. Second, requirement (b) governs the temporal dependence structure of . In particular, the bound implies that the reduced-form system is free from both unit-root behaviour and explosive dynamics. As a result, persistent yet stable propagation of shocks across the KRW exchange-rate network is permitted, while non-stationary or divergent trajectories are excluded from consideration.
Interpretation 1.
Condition 1 is formulated using the matrix norm . Since the inequality holds for any matrix , the norm is particularly well-suited for deriving upper bounds on products of matrices that involve transposition. This property is especially useful when analysing stability requirements in high-dimensional exchange-rate interaction systems.
Interpretation 2.
Condition 1 is closely related to requirements commonly imposed in the spatial econometrics literature, where an interaction parameter—often denoted by —is required to remain below unity and the associated weight matrix, such as , is appropriately normalised (Badinger and Egger [37]; Li and Guo [38]; Qiu et al. [39]). In that framework, the product , which serves as the conceptual analogue of the matrix , is usually bounded under constraints similar to . A standard normalisation strategy involves row-normalising so that each absolute row sum equals one, combined with the restriction . When is symmetric, it follows directly that . Within the context of a KRW-centred exchange-rate network, these restrictions can be interpreted as bounding the overall strength of contemporaneous cross-currency interactions to ensure a well-behaved and stable dependence structure. Beyond contemporaneous and dynamic cross-currency interactions, the dependence properties of the process are also shaped by the characteristics of the innovation sequence. To formalise these features, the following condition is imposed on the innovation process.
Condition 2.
The innovation series is assumed to exhibit covariance stationarity and behave as a martingale difference sequence relative to the given filtration , while also satisfying a geometric strong mixing requirement with (. Specifically, the coefficients () governing stochastic dependence, obey for all and regarding of some positive constants and . The least eigenvalue corresponding to the covariance matrix is bounded away from zero, and the matrix norm satisfies . It is assumed that at least one of the ensuing tail requirements is met: Regarding , it is required that for is greater than or equal to 4. Regarding , it holds that . In the spirit of Kock et al. [40] and Zheng [41]. Condition 2 imposes regularity requirements on the stochastic structure of the innovation process . This requirement ensures that the influence of past shocks decays sufficiently fast over time and restricts serial and cross-sectional dependence across exchange-rate innovations. The martingale difference property implies , while the mixing requirement controls temporal dependence in the innovation sequence. Requirement governs contemporaneous dependence within the innovation covariance structure. A positive constant serving as a lower limit for the smallest eigenvalue of guarantees that every innovation component carries distinct content, whereas the upper bound on limits the aggregate intensity of inter-currency linkages, thereby ruling out degenerate or excessively correlated shock structures. Requirements impose polynomial and exponential tail decay, respectively, which directly specify the permissible expansion rates for the cross-sectional size and the time dimension . As demonstrated, Condition 2 accommodates a broad class of innovation processes relevant for high-frequency financial data, including exchange-rate returns. While Conditions 1 and 2 fully characterise Equation (2)’s reduced-form specification, contemporaneous interactions among variables may nonetheless introduce endogeneity issues. Because the variable enters both the dependent and explanatory parts of Equation (1), applying separate ordinary least squares to each equation does not yield consistent estimates of and . This problem can be mitigated using instrumental variable techniques (Krisztin and Piribauer [42]) or, alternatively, by applying the generalised Yule-Walker framework proposed by Hsu et al. [43] and utilised in this analysis. Given Conditions 1 and 2, multiplying Equation (1) by on the right-hand side and computing the expectations gives
By inserting consistent estimators for the population covariance matrices and into Equation (3), one obtains a corresponding set of equations that allows recovery of the structural coefficients and . Nevertheless, since each row of Equation (3) yields relations but involves unknown elements, additional identifying conditions are necessary to achieve a unique and consistent estimation of the parameters.
2.2. Structural Regularisation in High-Dimensional Systems
Several approaches are available for introducing structural restrictions into the coefficient matrices and . In earlier econometric frameworks, particularly those developed in spatial econometrics, interaction effects are commonly incorporated through a prespecified weighting structure. Representative examples include both SAR and the SD models, where cross-sectional dependence is encoded via the product , with the weight matrix fixed in advance. Under this formulation, imposing introduces a highly restrictive structure on contemporaneous interactions, reducing the estimation problem to a single scalar parameter . Subsequent contributions have relaxed this restriction by allowing for greater heterogeneity in interaction strengths. For instance, Parrella et al. (2021) [44] examine a framework where every cross-sectional unit possesses a distinct autoregressive parameter. In particular, they specify and , leading to the estimation of parameters collected in . More recently, Han and Lee [45] adopt an alternative strategy by imposing a banded structure directly on the matrices and . In line with this latter strand of the literature, a bandedness condition is also employed in the present framework. However, the admissible bandwidth is allowed to be substantially wider than that typically considered, which is particularly relevant in high-dimensional exchange-rate systems where economically meaningful spillovers may extend beyond immediate neighbours in an ordering based on trade intensity, financial exposure, or regional linkages.
Condition 3.
Let , , and . It is assumed that: for all , where ; and = 0 for all . Condition 3 serves dual purposes in the analysis. First, for each exchange-rate node , enforcing bandedness across matrices and guarantees that the set of parameters to be estimated within each equation remains no greater than . Given the availability of moment requirements for each equation, requirement (a) of Condition 3 represents the widest admissible bandwidth that still guarantees parameter identification. In numerous empirical contexts—including the KRW exchange-rate framework analysed here—the effective scope of interactions may, in reality, be more limited than the theoretical limit defined in Condition 3. Although a reduced bandwidth is not explicitly constrained or mandated, it inherently enhances sparsity, which the proposed estimation framework effectively utilises. Furthermore, Proposition 1 demonstrates that combining Condition 3 requirements leads the autocovariance matrices to exhibit an approximately banded structure. This property plays a pivotal role in the generalised Yule–Walker estimation approach, wherein a band-limited treatment of the autocovariance structures is adopted to improve the estimator’s rate of convergence under high-dimensional requirements. Although Condition 3 holds, the number of unidentified parameters in and can still expand quadratically with . As a result, precise estimation across all coefficients becomes unrealistic even for models of moderate scale. To alleviate this high-dimensional complexity, a sparsity constraint is imposed, which, in this framework, emerges when certain exchange-rate nodes lack direct interdependence once the broader currency network interactions are taken into account. A particular, and empirically tractable, sparsity pattern emerges when exchange-rate nodes are ordered in a structured manner reflecting economic proximity. To illustrate this mechanism, consider repeated observations on a set of exchange-rate nodes arranged according to a structured ordering. Such an ordering implicitly reflects degrees of economic closeness—based on trade exposure, financial integration, or regional affiliation—and suggests that cross-currency interactions are most pronounced at shorter economic distances. In the context of KRW bilateral exchange rates, shocks originating from major currencies or closely connected partners are therefore expected to transmit more strongly than those from economically distant nodes. Under this ordering, nonzero coefficients in the matrices and tend to concentrate along specific diagonals, corresponding to economically meaningful interaction ranges, with occasional zeros arising at the boundaries of the ordering. Interactions associated with more distant nodes remain located on diagonals further away from the main diagonal, albeit with diminishing importance. Since neither the relevant direction nor the effective range of these interactions is known a priori, a penalised estimation approach is adopted that is capable of detecting and efficiently estimating such diagonally structured sparsity patterns without imposing them ex ante. To provide a visual illustration of this mechanism, Figure 1 summarises how economically localised exchange-rate interactions translate into structured sparsity patterns. The figure links the ordering of exchange-rate nodes based on economic proximity to the resulting concentration of non-zero coefficients along a limited number of diagonals, thereby offering an intuitive representation of the banded structure formalised in Condition 3.
Figure 1.
Results of economically ordered exchange-rate interactions and the resulting banded sparsity structure: (a) Results of KRW-centred exchange-rate interaction network (economically ordered); (b) Results of Banded/diagonal sparsity implied by economic proximity.
3. Sparse Estimation Within the High-Dimensional KRW Exchange-Rate Framework
The empirical analysis relies on daily bilateral exchange-rate series for the Korean won against a broad set of major trading-partner and financial-market currencies. All exchange-rate data are obtained from established financial data providers, including Bloomberg and Refinitiv (Reuters), which ensure consistent coverage, standardised definitions, and reliable timestamping across markets. The sample spans the period 2019–2023 and is constructed to capture both regional and global dimensions of Korea’s foreign-exchange exposure. Prior to estimation, the raw exchange-rate series undergoes a systematic preprocessing procedure. All series are synchronised to a common trading calendar to ensure cross-currency comparability. Market holidays and non-trading days are handled by aligning observations across currencies, with isolated missing values addressed using multivariate time-series imputation methods that preserve the joint dependence structure. Basic data cleaning steps are applied to screen for recording errors and abnormal observations. Exchange-rate levels are then transformed into daily returns or log differences, which mitigates non-stationary behaviour and ensures consistency with the stability conditions imposed in the subsequent modelling framework.
This section introduces the estimation framework and the related theoretical results for a sparsity-based estimator of the spatio-temporal VAR described in Equation (1), emphasising its applicability to high-dimensional exchange-rate structures. Building upon the structured sparsity framework outlined earlier, the analysis leverages localised interaction regularities within coefficient matrices and , which are achieved through band-restricted estimation of empirical autocovariance matrices. The discussion begins by establishing finite-sample deviation bounds for these band-restricted covariance estimators, serving as empirical analogues to their population counterparts in the KRW-focused exchange-rate environment. These theoretical foundations underpin the subsequent development of the sparse estimator, followed by a detailed examination of its asymptotic properties, including consistency and convergence performance in high-dimensional requirements.
3.1. Localised Estimation of Autocovariance Structures
Condition 3 is central to the recoverability of the system coefficient matrices and , while simultaneously improving the accuracy with which the autocovariance objects appearing in Equation (3) can be estimated. While the inverse of a banded matrix typically lacks an exact banded configuration, the term , which represents the autoregressive parameters in the reduced-form model (2)-is not expected to exhibit strict bandedness. Nevertheless, owing to its dependence on and , can be closely represented by a matrix with a near-banded pattern in high-dimensional exchange-rate contexts. This observation implies that the autocovariance matrices of approximately share a banded form. Specifically, combining the near-banded characteristics of with the structural sparsity of suggests that correlations among exchange-rate nodes diminish as their economic separation increases. The subsequent proposition formalises this reasoning by demonstrating the approximate banded properties of the autocovariance matrices and deriving the finite-sample bounds associated with adopting a band-constrained estimation framework.
Proposition 1.
Establishes the rate of convergence for band-limited estimators derived from empirical autocovariance structures in high-dimensional exchange-rate frameworks, given a matrix , its . Using this operator, the matrix is constructed from the sample autocovariance matrices and , where the bandwidth is selected according to the rule specified in (4).
For and appropriately defined constants and , the proposition establishes that holds with high probability. The resulting probability bounds are determined by the tail properties of the exchange-rate shock process. Specifically, case (a) pertains to the setting where Conditions 1–3 are imposed jointly with the polynomial-type requirement in Condition 2, whereas case (b) corresponds to the alternative specification in which Conditions 1–3 are coupled with the exponential-type requirement stated in Condition 2. The associated probability expressions are characterised by the functions and , whose magnitudes depend on the bandwidth , the time dimension , and the cross-sectional dimension . The constants and , for , are positive and do not depend on either or . Moreover, belongs to . Proposition 1 establishes that the banded estimators of and deliver accurate approximations to in high-dimensional exchange-rate systems. Each band-restricted matrix features at most active entries along any row or column, leading to a pronounced contraction of the effective dimensional scale. Consequently, for fixed values of , , and , the requirements imposed in Conditions 1–3 guarantee that the population-level autocovariance operators and admit accurate representations through matrices whose effective bandwidth remains well below the ambient dimension . Leveraging this property, the following section constructs a sparsity-based estimator for the system coefficient matrices and demonstrates that such structural approximability of the underlying autocovariance objects yields sharper asymptotic convergence behaviour for the estimator within the KRW-centred exchange-rate setting.
3.2. A Sparse Spatio-Temporal Estimator Based on the SPLASH Framework
The following discussion develops an estimation strategy designed for high-dimensional exchange-rate environments, building on the model specification in (1) and accommodating complex spatio-temporal dependence structures. The methodology combines a Yule–Walker–type estimating framework with a structured penalisation scheme that promotes sparsity, drawing conceptual inspiration from recent regularisation-based approaches such as Tugnait [46]. The Yule–Walker equations are employed to address the endogeneity induced by contemporaneous interactions among exchange-rate nodes, while the penalty component encourages coefficient estimates to conform to the diagonally structured sparsity patterns illustrated in Figure 1. Relative to the framework of Sun and Malikov [47], this specification enables the exploitation of sparsity within the prespecified bandwidths of the coefficient matrices and . As a result, the estimator remains capable of accommodating substantially wider bandwidth choices without materially compromising estimation accuracy. This flexibility is particularly relevant in KRW-centred exchange-rate networks, where economically meaningful spillovers may extend beyond immediate neighbours defined by trade intensity, financial exposure, or regional linkages.
3.2.1. Formal Definition of the Proposed Estimator
The derivation of the proposed estimator relies on supplementary symbols and definitions, many of which stem from a streamlined reformulation of the Yule–Walker–type system. Accordingly, the set of Yule–Walker relations stated in Equation (3) admits a concise representation in matrix notation.
In Equation (5), the column of aggregates the parameters corresponding to the structural relation in Equation (1). Imposing Condition 3 enforces sparsity by setting a subset of these parameters identically to zero, thereby removing them from further consideration. The coefficients that remain admissible in the relation are stacked into the parameter vector , while the associated columns of are collected into the matrix . At the population level, this formulation yields the identity with , where denotes the canonical basis vector of dimension . Empirical counterparts of and are constructed directly from the sample autocovariance estimates. In line with Mesters and Koopman (2014) [48], the vector is obtained as , using the relevant block components of . Guided by the population restriction , the generalised Yule–Walker estimator is obtained by minimising the associated quadratic loss function.
The objective function is refined along three complementary dimensions. First, the estimator is reformulated using banded estimators of the covariance matrices, thereby incorporating the approximate dependence structure implied by economically localised interactions among KRW exchange-rate nodes. Second, sparsity in the system’s coefficient matrices is induced through a blockwise regularisation strategy. In order to reflect the diagonal-oriented sparsity configurations depicted in Figure 1, diagonal elements are treated as unified groups and subjected to joint shrinkage whenever such patterns arise. A direct implication of this design choice is that the parameters can no longer be estimated separately on an equation-specific basis. In light of the banding operators introduced in Proposition 1, let , , where collects those columns of that correspond to the components of (Figure 2 for a graphical illustration). The regularisation scheme is then specified by decomposing the coefficient vector c into a family of subvectors , each associated with a permissible nonzero diagonal block of the coefficient system implied by Condition 3. In particular, the relevant index sets are defined as follows.
Figure 2.
Results of constructing under banded admissibility and active-set selection: (a) Results of admissible nonzero locations in and (h = 1); (b) Results of with active columns highlighted. (c) Results of submatrix extracted from .
In Equation (7), . With the above definitions in place, the estimation criterion can be written in the following form:
In Equation (8), the penalty term is given by . The resulting estimator adopts a spatially regularised lasso-type formulation and is denoted by SPLASH(, or simply SPLASH. It is obtained by solving the optimisation problem in (8), namely . The penalty level controls the global intensity of shrinkage, whereas the mixing parameter α\alphaα governs the relative emphasis placed on groupwise versus componentwise regularisation. The boundary choices and recover the pure group-based and elementwise shrinkage schemes, respectively. For values of strictly between these extremes, the procedure simultaneously encourages diagonal-level shrinkage across the system coefficient matrices and sparsity within diagonals that remain active, steering the estimator toward the structured configurations illustrated in Figure 1b.
3.2.2. Computational Implementation of the Proposed Estimator
The SPLASH estimator is implemented through a well-organised workflow, the full description of which is provided in Algorithm S1 in Supplementary Materials. The procedure can be decomposed into three stages: first, specifying an appropriate banding level ; second, calibrating the regularisation parameters and ; and third, solving the associated optimisation problem defined by the objective function . Theoretical justifications for the first and third stages are documented in the methodological references cited in connection with algorithm. Parameter calibration is carried out via cross-validation techniques adapted to time-series settings, ensuring that the chronological structure of the exchange-rate observations is preserved. The candidate grids proposed in Algorithm S1 serve as empirical benchmarks rather than binding prescriptions. While denser grids may improve numerical accuracy, they also entail higher computational costs, which can become non-negligible in high-dimensional KRW exchange-rate applications. In settings with constrained computing capacity, the search space may be reduced by fixing one hyperparameter—for instance, setting and optimising solely over . Importantly, users are not required to implement the optimisation Algorithm S1 from scratch. A dedicated MATLAB package (v. 2025a) has been developed to provide a fast and scalable realisation of the SPLASH estimator, enabling straightforward application to large exchange-rate panels. The implementation explicitly accounts for the structured sparsity configurations illustrated in Figure 1 and Figure 2 and is well-suited for empirical investigations of high-dimensional KRW-centred currency networks. The regularisation parameter is selected using a time-series cross-validation procedure that preserves the temporal ordering of the data. For each rolling window, is chosen from a logarithmically spaced grid bounded by the smallest value that yields a non-degenerate solution and the largest value that collapses the estimator to the null model. This window-specific selection avoids look-ahead bias and allows the degree of regularisation to adapt to evolving dependence structures in the exchange-rate system. Empirically, the resulting estimates and forecasting performance are stable across a wide range of admissible values, indicating that the main findings are not driven by a particular tuning choice.
3.2.3. Asymptotic Properties of the Proposed Estimator
To secure point identification of the system parameters in Equation (1) for high-dimensional exchange-rate settings, an extra requirement on the underlying stochastic mechanism is imposed. This requirement extends the restrictions introduced in Condition 3 and establishes identifiability by enforcing a simple non-degeneracy criterion on suitably chosen blocks of the autocovariance operators involved in the Yule–Walker representation. Within a KRW-centred exchange-rate environment, the requirement captures the notion that economically relevant cross-currency linkages generate enough independent variation to disentangle contemporaneous effects from dynamic transmission channels.
Condition 4.
Let . This condition stipulates that every submatrix of obtained by choosing no more than columns is free of rank deficiency, with its smallest singular value bounded uniformly away from zero. Similar requirements have been studied in the high-dimensional regression literature, notably by Liu et al. (2012) [49], who refer to as a restricted eigenvalue to establish sufficient requirements for restricted eigenvalue conditions. This condition is particularly well aligned with the present framework. Imposing Condition 3 places an explicit restriction on the admissible bandwidth of the coefficient matrices, which guarantees that each diagonal block of involves at most unique columns drawn from . Leveraging this feature, Auxiliary Result 1 reported in Supplementary Materials establishes that the requirements for Sparse Group Lasso compatibility follow directly from Condition 4. When combined with this condition, it becomes possible to obtain nonasymptotic performance bounds for both the predictive accuracy and the parameter recovery of the SPLASH estimator in high-dimensional KRW exchange-rate applications.
Proposition 2.
Introduces the quantity , with and . When Conditions 3–4 are satisfied, and the matrix obeys the bound , one obtains the following inequality.
Inequality (9) is satisfied with high probability. Specifically, under the scenario associated with Condition 2, which allows for polynomial-type tail behaviour, the bound holds with probability no smaller than . Under the alternative regime characterised by Condition 2, corresponding to exponential-type tails, the same inequality is guaranteed with probability at least . The probability functions and are specified in Proposition 1, and the quantity is defined as . Building on these results, Proposition 2 establishes non-asymptotic guarantees for both predictive accuracy and parameter recovery of the SPLASH estimator in high-dimensional KRW-centred exchange-rate settings.
The result quantifies how the interaction between the structured sparsity pattern, the regularisation parameters , and the restricted minimum eigenvalue requirement governs the accuracy of estimating contemporaneous and dynamic spillover effects across currencies. In particular, the bound in (9) shows that, under economically localised cross-currency dependence, the SPLASH estimator achieves controlled estimation error even when the dimensionality of the exchange-rate system is large relative to the available time-series length. Proposition 2 establishes non-asymptotic performance guarantees for the SPLASH estimator, quantifying its accuracy in terms of both forecasting performance and parameter recovery within high-dimensional exchange-rate systems. This result gives rise to several noteworthy insights. In particular, emphasis is placed on the likelihood under which requirement (9) is satisfied. In standard VAR frameworks estimated through regularised least-squares techniques, such likelihood statements are commonly governed by the distributional behaviour of accumulated stochastic components associated with regression errors, as documented for instance in Kock and Callot [50]’s Auxiliary Result 4 and Medeiros and Mendes [51]’s Auxiliary Results 5–6. In contrast, since the present framework depends on generalised Yule–Walker estimation, the probability bound in (9) is governed by the tail behaviour of , which is directly linked to the accuracy of banded autocovariance matrix estimation established in Proposition 1. As a result, faster tail decay of the exchange-rate innovations enhances the likelihood that the bound in (9) is satisfied, as reflected in the comparison between cases (a) and (b). Second, the structure of the upper bound in (9) provides insight into the determinants of estimation performance. The magnitude of the bound is increasing in , which itself expands as the allowable bandwidth parameters and become larger, as the size of the penalised blocks rises in regimes with , and as the cardinality of the interaction set grows whenever . Moreover, stronger regularisation results in looser bounds for both prediction and estimation errors. While this pattern might seem to support choosing smaller values of , Proposition 2 reveals an inherent trade-off: enlarging deteriorates the tightness of the bound but, at the same time, increases the likelihood of the underlying event for which the bound remains valid. From an intuitive perspective, shrinkage introduces finite-sample bias that reduces pointwise accuracy, but it also dampens sensitivity to noise, thereby yielding performance guarantees with higher confidence. These effects can also be examined through an asymptotic lens. Building on Proposition 2, the subsequent theorem derives sufficient requirements under which prediction and estimation errors converge, together with explicit convergence rates that describe the behaviour of the SPLASH estimator in high-dimensional KRW exchange-rate panels.
Theorem 1.
Let , , , , , where , , and are fixed positive constants. Maintain Conditions 1–4 and suppose that either (i) and Condition 2 holds, or (ii) and Condition 2 holds. Then, the SPLASH estimator achieves convergence of both prediction and estimation errors in high-dimensional KRW exchange-rate systems (a). . (a) describes the asymptotic order of the squared prediction error associated with the banded design matrix . In high-dimensional KRW exchange-rate systems, this rate reflects the combined impact of structured sparsity, cross-currency dimensional growth, and admissible interaction ranges. The two components in the bound correspond to group-level shrinkage effects, weighted by , and elementwise sparsity effects, weighted by . Together, these terms characterise how the complexity of contemporaneous and dynamic spillovers across currencies influences prediction accuracy as the system dimension increases with the sample size. (b) . (b) provides the corresponding asymptotic behaviour of the estimation error measured by the mixed penalty . The expression highlights the role of group-structured sparsity through the summation over admissible diagonal groups and the contribution of individual coefficient shrinkage through the component. In the context of KRW-centred exchange-rate panels, this result clarifies how the balance between group sparsity and individual sparsity—regulated by the tuning parameter -interacts with the growth rates of the cross-sectional dimension and sparsity measures to determine the consistency properties of the SPLASH estimator. Theorem 1 clarifies the key factors governing the convergence behaviour of the SPLASH estimator in high-dimensional exchange-rate settings. The analysis indicates that the speed of convergence weakens when the permissible bandwidth parameters and become larger, when the dimensionality of the system—as measured by the number of currencies —increases, when the set of economically relevant cross-currency linkages becomes richer, and when the regularisation intensity is strengthened. These patterns are symptomatic of the growing structural and statistical complexity of the KRW-centred exchange-rate network as additional currencies and interaction pathways are introduced. or the probability statement underlying the finite-sample bound in Proposition 2 to hold asymptotically, requirements (i) and (ii) restrict how fast the regularisation parameter may decline as the sample size expands. In essence, the shrinkage level cannot be relaxed too aggressively, as doing so would undermine control over estimation error in a high-dimensional setting. Subject to these limitations, the fastest attainable rate of convergence is obtained by choosing the tuning exponent at the upper edge of the admissible range defined by the imposed requirements. Illustrative discussions of these trade-offs are presented in Interpretation 3.
Interpretation 3.
A number of instructive scenarios follow as direct consequences of Theorem 1 when attention is restricted to the behaviour of the estimation discrepancy under moment requirements ensuring that the innovation sequence possesses at least bounded moments, as formalised in Condition 2. To begin, consider the configuration in which no shrinkage is imposed at the group level, which corresponds to setting . Under this specification, Theorem 1 yields , provided that the regularisation exponent satisfies . The associated estimator therefore attains a convergence speed arbitrarily close to , which, when the cross-sectional dimension is held constant and the moment order becomes sufficiently large, approaches the classical -type rate familiar from low-dimensional settings without penalisation. By contrast, when regularisation is applied solely at the level of individual interactions, corresponding to the choice , the discrepancy obeys , and the resulting rate simplifies to . Since dominates , it follows that the SPLASH estimator attains a convergence performance that is no slower—and in many cases strictly superior—than that of SPLASH, particularly when sparsity lacks a clear group structure or when only a small subset of diagonals in the coefficient matrices and is effectively active. In the context of KRW-centred exchange-rate systems, this comparison highlights how the choice of affects the relative efficiency of exploiting structured versus unstructured sparsity, depending on whether cross-currency spillovers are concentrated along economically meaningful interaction channels or dispersed across individual exchange-rate pairs.
3.2.4. Extensions to Model Selection and Statistical Inference
This analysis naturally points to several avenues along which the proposed methodology may be further advanced in the context of high-dimensional exchange-rate modelling. One line of extension focuses on achieving reliable variable screening, whereas another is concerned with the construction of statistically sound inference procedures for large-scale KRW-centred currency systems. A promising direction involves enriching the penalisation scheme by allowing coefficient-specific weights, thereby introducing adaptivity into the regularisation mechanism. This idea is conceptually related to the adaptive shrinkage principle introduced by Zou [52]. Incorporating such weights is expected to enhance the ability of the estimator to correctly identify zero coefficients with asymptotic probability one, while maintaining consistent estimation for the remaining active parameters appearing in Equation (1). Formally, an adaptive variant of the estimator may be obtained by minimising the objective function , where represents the total number of parameters in the system. Compared with the criterion in Equation (8), the weight vector assigns differential shrinkage intensities across coefficients, placing relatively higher penalties on components that are empirically small and weaker penalties on those exhibiting stronger signals. A convenient specification satisfying this principle is for some , where denotes the element of the SPLASH estimator obtained from (8). A rigorous assessment of the asymptotic behaviour and finite-sample properties of this adaptive extension—including its selection accuracy and inferential performance in exchange-rate networks—is deferred to future work. An additional research direction concerns the development of dependable inference tools for high-dimensional exchange-rate systems estimated via sparse regularisation. Two major obstacles are commonly encountered in this setting. The first arises from the complexity of the asymptotic distribution, which typically involves unknown nuisance components and lacks a closed-form representation (Knight and Fu [53]). The second reflects the absence of uniform convergence across the parameter space, thereby invalidating standard asymptotic approximations. One potential remedy is to construct a bias-corrected version of the SPLASH estimator that facilitates uniformly valid inference. Such a procedure may be formulated by exploiting the optimality requirements of the penalised optimisation problem and reversing their effect, in a fashion comparable to the desparsification strategy developed by Zhang and Zhang [54]. Adapting this approach to the present framework, however, necessitates additional methodological adjustments to account simultaneously for the banded dependence structure of the autocovariance matrices and the group-oriented regularisation embedded in SPLASH. A comprehensive theoretical analysis of these extensions falls outside the remit of the current contribution and is reserved for subsequent research.
3.3. Incorporation of Exogenous Covariates
The baseline formulation in Equation (1) is augmented to include externally determined covariates, yielding the following representation.
In Equation (10), the time index ranges over . For each , the -dimensional vector = ( serves to extend the underlying spatio-temporal vector autoregressive system by incorporating an external covariate that influences bilateral KRW exchange-rate dynamics. These regressors may evolve over time and are assumed to be strictly exogenous, implying for all k = 1. Within the exchange-rate setting, such variables can represent global financial requirements, international monetary or policy shocks, or other macroeconomic influences that originate outside the endogenous currency interaction network. To incorporate exogenous influences into the exchange-rate framework, the generalised Yule–Walker estimator introduced in Section 3.2 is accordingly adapted. Recall that , and define the cross-moment matrices and . Within the context of KRW bilateral exchange rates, these matrices summarise the dynamic comovement between external drivers and the currency network at different lags. Two collections of Yule–Walker identities are derived by right-multiplying the system with lagged regressors and seasonal components, after which expectations are taken. This procedure leads to the formulations reported in Equations (11a) and (11b).
In Equations (11a) and (11b), belongs to . Relative to the baseline system in (5), Equation (11a) contains the additional term , which conveys information about the coefficients capturing the impact of exogenous forces on KRW exchange-rate dynamics. However, when for instance, if the exogenous variables are orthogonal to the endogenous exchange-rate process or if Equation (11a) alone is insufficient to identify . For this reason, the supplementary Yule–Walker relations in (11b) are introduced to ensure identification. To construct the estimator in a compact form, Equations (11a) and (11b) are stacked and combined as
Subsequent steps in the development of the SPLASHX estimator adhere to the structural blueprint established in Section 3.2.1, with suitable modifications to accommodate a KRW exchange-rate framework incorporating external driving variables. Attention is first restricted to the exchange-rate node, and all coefficients of and that are potentially nonzero under Condition 3 are collected in the vector . Let denote the columns of associated with , and define together with . Then, result (12) implies the relation , which links endogenous exchange-rate interactions and exogenous influences at the level of a single KRW bilateral rate. Next, sample analogues of the population moments are introduced. Specifically, the matrices , , and are replaced by their empirical counterparts , , and . Based on these quantities, the corresponding estimators , , and are constructed. Stacking across exchange-rate nodes yields , , and . The SPLASHX estimator is obtained by solving the associated optimisation problem.
This formulation permits joint estimation of the vectors , which may exhibit sparse entries or be entirely zero, alongside sparse diagonal structures in the coefficient matrices and . The mathematical structure of SPLASHX closely parallels that of the baseline SPLASH estimator. Consequently, under suitably adjusted versions of Conditions 1–4, results analogous to Proposition 2 can be established. For expositional transparency, the link between the baseline conditions and their extended versions is clarified by preserving the existing labels while marking the latter with a superscript “*”. An overview of these revised requirements is presented in the concluding part of the present section.
Condition 5.
The following regularity requirements are imposed to ensure a well-behaved KRW exchange-rate system with exogenous drivers. The contemporaneous interaction matrix satisfies , which restricts the overall strength of instantaneous cross-currency spillovers. (b) The lagged dependence matrix obeys together with , thereby guaranteeing stable dynamic propagation of exchange-rate shocks. (c) The magnitudes of the coefficients associated with exogenous variables are uniformly bounded, such that , ensuring that external influences on KRW bilateral exchange rates remain controlled.
Condition 6.
The stochastic setting governing the KRW-centred exchange-rate system with external covariates is characterised as follows. (a) Consider any pair of distinct cross-sectional indices , any ordered time points , and any covariate index . The external regressor is probabilistically independent of the innovation component . This restriction formalises the strict exogeneity of the observed drivers relative to exchange-rate shocks across both currencies and time.
(b) The innovation process is assumed to be second-order stationary and satisfies the martingale difference property with respect to the information set . Moreover, the process exhibits geometric strong mixing, with associated coefficients decaying exponentially in the sense that for all , where and are fixed constants. In addition, the spectrum of the innovation covariance matrix is uniformly bounded, ensuring non-degenerate contemporaneous shock dependence across currencies. (c) For every external component indexed by , the corresponding regressor sequence is covariance stationary and satisfies a geometric α-mixing requirement. Specifically, its mixing coefficients decay at an exponential rate, i.e., for all , with positive constants and . This requirement limits serial dependence in the external drivers affecting bilateral KRW exchange rates. (d) One of the following moment restrictions is imposed. (d1) If the moment function is given by with , then both the innovations and the external regressors admit uniformly bounded moments of order , that is, , , for each external index . (d2) Alternatively, if , then both and satisfy uniformly bounded exponential-type moment requirements, with finite constants for all admissible indices.
Condition 7.
It recalls that , , and . The following structural restrictions are imposed to reflect economically localised dependence in the KRW exchange-rate network. (a) The contemporaneous and lagged interaction coefficients satisfy for all , where the bandwidth parameter obeys . This requirement limits direct spillovers to exchange-rate pairs that are sufficiently close under the chosen economic ordering. (b) The innovation covariance matrix exhibits a similar banded structure, with is equal to 0 regarding to all , thereby restricting contemporaneous cross-currency shock dependence to a finite interaction range.
Condition 8.
It provides a definition of matrix . It is assumed that the matrix satisfies a constrained minimum eigenvalue requirement, namely . This requirement ensures that, within the KRW exchange-rate system augmented by exogenous drivers, any sufficiently sparse linear combination of contemporaneous, lagged, and external components is well identified. In economic terms, this condition rules out near-collinearity among the relevant exchange-rate interactions and external influences, thereby guaranteeing that the generalised Yule–Walker equations retain enough informative variation to distinguish endogenous cross-currency spillovers from the effects of exogenous shocks. Conditions 5 retain the same role as in the baseline setting, while Condition 5 imposes a uniform upper bound on the magnitude of coefficients associated with exogenous drivers in the KRW exchange-rate system. Condition 6 governs dependence structures along three dimensions: temporal dependence, cross-currency dependence, and interactions between exchange-rate innovations and exogenous regressors. In line with the condition of Ma et al. [55], strict exogeneity is enforced through Condition 6, ensuring that external variables are orthogonal to the innovation process. Condition 6 directly mirrors Condition 2 for exchange-rate innovations, while the corresponding dependence requirements for the exogenous sequences are formalised in Condition 6. All moment restrictions originally imposed on the innovation process are likewise extended to the exogenous regressors through Condition 7. Taken together, Conditions 5–8 preserve a transparent one-to-one correspondence with these conditions introduced earlier in this paper, albeit with a trade-off in potentially stronger restrictions than strictly required. To clarify this correspondence, define the composite disturbance term , and note that is linear in both the original exchange-rate innovations and the exogenous regressors . Since the number of exogenous variables is fixed, all mixing properties and moment requirements imposed on the original processes naturally extend to . Under these modified conditions accommodating exogenous influences, the arguments underlying Proposition 2 remain valid, allowing the result to be extended to the KRW exchange-rate framework with external drivers and yielding an error bound that remains valid in finite samples.
Proposition 3.
Let the parameter vector be defined as and denote by , the corresponding active index set. Define the quantity . Suppose that Conditions 5–8 are satisfied and that the matrix obeys the bound . Then the estimator obeys the inequality . This inequality holds with probability no smaller than when the innovation distribution satisfies Condition 2, corresponding to polynomial-type tail behaviour, or , under Condition 2, which allows for exponentially decaying tails. Here, . The probability terms are given by , , and . All constants appearing above () are strictly positive, do not depend on and , and coincide with those introduced in Proposition 1.
Interpretation 4.
Incorporating external covariates leads to modifications in the underlying autocovariance characteristics of the KRW exchange-rate framework. To illustrate this effect, consider the special case in which . In this situation, the exchange-rate vector admits the representation , which implies that . This expression makes explicit that the contemporaneous covariance matrix now depends not only on the innovation covariance but also on the second-moment properties of the exogenous covariates driving KRW bilateral exchange rates. No parametric or structural restrictions are imposed a priori on . Consequently, the SPLASHX estimator is formulated using unbanded estimators of the relevant autocovariance matrices, thereby allowing the data to fully determine how external drivers shape the dependence structure of the KRW exchange-rate network.
Interpretation 5.
Specifying the coefficient matrix premultiplying as diagonal does not impose a substantive restriction in the context of KRW exchange-rate modelling. This formulation serves primarily as a notational device rather than a limitation on economic transmission channels. By allowing to represent a suitably reordered version of , the model can equivalently accommodate situations in which a given KRW bilateral exchange rate is affected by the same exogenous driver originating from multiple exchange-rate nodes. Consequently, the diagonal structure does not preclude cross-currency exposure to external shocks but instead provides a flexible representation that can be adapted through appropriate reindexing of the exogenous variables.
4. Finite-Sample Performance and Simulation Evidence
4.1. Design of the Monte Carlo Experiments
The small-sample properties of the estimator proposed in this study are evaluated by means of a sequence of Monte Carlo exercises constructed to mirror the characteristics of a KRW-centred exchange-rate system. Synthetic data are generated according to the spatio-temporal vector autoregressive framework specified in Equation (1), which is designed to reflect both contemporaneous linkages and dynamic propagation mechanisms within a large cross-section of bilateral currency returns. The time dimension is chosen as , a range that aligns with sample lengths typically observed in empirical analyses based on daily exchange-rate data. Innovation terms are drawn independently from a standard Gaussian distribution , capturing idiosyncratic disturbances at the individual currency-pair level. The coefficient matrices and , together with the system dimension , are configured according to two distinct experimental designs outlined below, each representing alternative dependence structures that are empirically relevant for KRW-based exchange-rate networks. All numerical results reported in this section are obtained from independent replications, providing a stable basis for assessing estimation precision and finite-sample behaviour across the different scenarios considered.
Design A (Neighbourhood-Based Exchange-Rate Dependence). Guided by the network configuration depicted in Figure 1, the simulation environment is constructed by arranging exchange-rate units on an m × mm\times mm × m grid. Choosing and leads to cross-sectional dimensions of and , respectively. The contemporaneous dependence structure is encoded in the matrix , where each exchange-rate unit is linked exclusively to its nearest neighbours along the horizontal and vertical directions of the grid, and all other potential connections are suppressed. Each active contemporaneous linkage is assigned a constant strength of 0.2, representing localised spillover effects among closely connected KRW bilateral exchange rates. Temporal dynamics are governed by the matrix , which is specified to be diagonal, with diagonal entries set to 0.25 when and to 0.21 when , thereby capturing persistence at the level of individual exchange rates. Under these parameter choices, the implied reduced-form VAR coefficient matrix exhibits a dominant eigenvalue equal to 0.814 for and 0.904 for . Both values lie strictly below unity, guaranteeing dynamic stability in line with the structural restrictions imposed on the KRW-centred exchange-rate system. Design B (Banded Specification for KRW Exchange-Rate Dynamics). The simulation framework is constructed by tailoring the initial Monte Carlo design proposed in Okui [56] to a KRW-centred exchange-rate context. Both the contemporaneous interaction matrix and its dynamic counterpart are assumed to exhibit localised dependence, implemented through a band-limited structure with a pre-specified interaction range . The entries of these matrices are generated according to a multi-step mechanism. Step 1. For coefficient positions located exactly at the boundary of the interaction range, that is, index pairs satisfying , the associated parameters and are independently sampled from a symmetric two-point distribution taking values in {−2,2}. For all other admissible positions within the interaction range, coefficients are drawn from a mixed distribution that assigns positive probability to zero outcomes and otherwise follows a standard Gaussian law, with mixing probabilities equal to 0.4 and 0.6, respectively. This design induces sparsity while preserving heterogeneity in cross-rate dependence among neighbouring KRW bilateral pairs. Step 2. To regulate the overall strength of contemporaneous and dynamic interactions, the resulting coefficient matrices are normalised via random scaling. Specifically, each matrix is multiplied by an independent scaling factor sampled from the uniform distribution on the interval [0.4,0.8], ensuring comparable magnitudes across simulation replications. Step 3. System stability is enforced by verifying that the spectral requirement holds. Whenever this criterion is violated, the generated matrices are discarded, and the data-generating procedure is restarted from the initial step. The cross-sectional dimension is allowed to vary across , enabling an assessment of finite-sample behaviour under both moderately sized and highly dimensional KRW exchange-rate network configurations.
The two experimental designs are specified to enable a symmetric assessment of modelling approaches that impose interaction structures through externally fixed spatial weighting schemes and alternatives that recover cross-sectional dependence patterns endogenously from the data within the KRW-centred exchange-rate environment. The benchmark methods employing predetermined spatial weights are drawn from Yu et al. [57] and Lam and Souza [58]. The estimator proposed by Yu et al. [57] is based on a spatio-temporal autoregressive specification (hereafter denoted ST-AR), in which spatial dependence and temporal dynamics are parameterised by three scalar coefficients together with a single spatial weight matrix. Estimation is conducted via Gaussian quasi-maximum likelihood. In comparison, the methodology proposed by Lam and Souza [58], known as LaSo, permits localised sparsification around a pre-specified spatial weighting scheme, thereby offering a more adaptable modelling device than standard spatial autoregressive specifications. To maintain consistency with the experimental configurations adopted in this study, the lagged term is incorporated into the regressor set in accordance with the modelling choice described in Section 3.2.4. For each of the competing benchmark procedures, the spatial weighting scheme is specified to mirror the nearest-neighbour interaction pattern embedded in Design A. By construction, this specification matches the assumed spatial dependence with the actual data-generating mechanism underlying Design A, thereby placing the benchmark approaches in a comparatively advantageous position under that scenario. At the same time, the same specification induces deliberate misspecification under Design B, where the underlying interaction pattern deviates from the nearest-neighbour structure. This contrast highlights the relative performance of approaches based on fixed spatial weights versus estimators that recover KRW exchange-rate interactions directly from the data. The second class of approaches infers spatial interactions directly from the data rather than imposing a predefined structure. Three variants of the SPLASH estimator are considered in the KRW exchange-rate setting. Specifically, (1) SPLASH targets sparsity exclusively at the group level, (2) SPLASH assigns equal importance to group-wise and element-wise sparsity, and (3) SPLASH promotes unstructured sparsity only. Consistent with Propositions 1 and 2, estimation relies on banded autocovariance matrices and , with bandwidths selected via the bootstrap procedure. For comparison, the generalised Yule–Walker estimators are included as benchmarks and denoted by GMWY and GMWY. The former implements generalised Yule–Walker estimation for banded coefficient matrices and using the data-driven selection rule in Equation (2.17) of their study. More precisely, the three SPLASH specifications differ in their treatment of sparsity: SPLASH enforces shrinkage solely at the block level, SPLASH balances structured and unstructured sparsity components, while SPLASH focuses exclusively on element-level regularisation.
In line with the theoretical results established in Propositions 1 and 2, estimation is conducted using band-restricted versions of the autocovariance matrices, namely and , where the truncation parameter is determined through the bootstrap-based selection procedure. As reference methods, generalised Yule–Walker estimators are also considered and labelled as GMWY and GMWY. The former applies a generalised Yule–Walker framework to coefficient matrices exhibiting banded dependence, with the tuning parameter chosen according to the data-driven criterion reported in Equation (2.17) of that study. In light of relatively weak performance observed for this estimator in preliminary simulations under Design B, the latter benchmark, GMWY, is constructed by supplying the true bandwidths of and , even though such information is infeasible in practice. To maintain comparability with the original simulation setup, neither GMWY estimator applies banding to the covariance matrix estimators and . Additional exploratory simulations indicate that the performance of the GMWY estimators is largely unaffected by whether banded covariance estimators are employed, and this specification is therefore retained in the reported results.
Finally, an additional benchmark based on a -penalised reduced-form VAR(1) is included and referred to as PVAR. Specifically, the reduced-form VAR(1) representation is considered, and the coefficient matrix is estimated by minimising . This estimator has been extensively studied in the time-series and high-dimensional VAR literature (Masini et al. [59]), while operating in a different context that differs from spatio-temporal exchange-rate modelling. Introducing the reduced-form VAR as a reference point makes it possible to explicitly evaluate whether improvements in forecasting performance stem from incorporating cross-currency interaction mechanisms rather than from specifications that account only for temporal dynamics. For the KRW exchange-rate system, such a comparison clarifies the relative contribution of contemporaneous linkages and network-type dependence vis-à-vis dynamics driven exclusively by lagged exchange-rate variations. Forecast accuracy across competing estimators is assessed through the Relative Mean Squared Forecast Error (RMSFE). Denote by the superscript an individual Monte Carlo replication. The RMSFE measures one-step-ahead predictive precision for each method relative to the benchmark VAR model and is calculated as follows.
Values below unity indicate superior forecasting performance relative to the benchmark, whereas values above unity reflect inferior predictive accuracy. In the context of KRW exchange rates, this metric highlights the extent to which modelling contemporaneous and network-based interactions improves out-of-sample forecasts. The performance of the spatio-temporal estimation methods is evaluated by means of the Mean Estimation Error (MEE). For each replication indexed by , this criterion is constructed as follows.
This measure summarises the average deviation between the estimated and true coefficient matrices governing contemporaneous and dynamic exchange-rate interactions. To quantify the dispersion of estimation accuracy across Monte Carlo replications, the standard error of the MEE is also reported. It is calculated as
Together, these measures provide a comprehensive assessment of both forecasting and estimation performance for high-dimensional KRW exchange-rate models, capturing not only average accuracy but also the variability of estimator behaviour across simulation trials. Next, the procedure used to determine hyperparameters is outlined. For each regularised procedure, the tuning parameter is explored over a sequence of candidate values arranged on a logarithmic scale. The largest element of this sequence, denoted by , is chosen as the minimal level of penalisation that collapses the estimator to the null solution (Step 4 of Algorithm S1 for the closed-form characterisation in the SPLASH case). Given , the lower endpoint of the grid is specified as , where under Design A and under Design B. Computing the complete collection of SPLASH estimates for all combinations of , , and every Monte Carlo replication is infeasible when the cross-sectional dimension is large. To mitigate this computational burden, a preliminary calibration step is carried out using a restricted subset of replications drawn from Designs A and B, evaluated at a fixed sample length . Within this reduced experiment, the index that delivers the smallest RMSFE is identified. Selecting from a logarithmically spaced grid is equivalent to fixing the penalty level at , where for Design A and for Design B. Under Design A (Design B), the selected indices are for , which correspond to multipliers (, respectively. Once this order of magnitude is fixed, estimation proceeds by computing the SPLASH estimator solely over the grid . In contrast, the penalised VAR benchmark entails substantially lower computational costs. Its regularisation parameter is therefore selected via a rolling time-series cross-validation procedure, consistent with standard practice (Hyndman and Athanasopoulos [60]). Since exploratory results indicate that transferring the SPLASH-based tuning rule leads to inferior outcomes for the LaSo estimator, the same cross-validation strategy is adopted for LaSo as well. Specifically, the initial 80% of the sample is used for model estimation, while forecast accuracy is assessed over the remaining 20% using the MSFE criterion. The final tuning parameter is chosen as the value that minimises this out-of-sample error measure. Across both simulation designs, performance measures vary smoothly over the grid, and the relative ranking of competing methods remains unchanged, indicating limited sensitivity to moderate variations in the regularisation level.
4.2. Monte Carlo Evidence for KRW Exchange-Rate Dynamics
To facilitate a transparent and economically grounded interpretation of the simulation outcomes, the results are summarised in Table 1, which reports forecasting and estimation performance across the two data-generating designs. These designs are constructed to reflect salient features of the KRW exchange-rate environment, including localised spillovers among closely connected currencies and broader dependence structures that arise in more complex international settings. By varying both the cross-sectional dimension and the sample length, the table allows for a systematic assessment of how model performance evolves with dimensionality and information availability. Presenting the results in a unified framework makes it possible to compare methods that impose interaction structures ex ante with those that recover exchange-rate linkages directly from the data, thereby clarifying the requirements under which high-dimensional, network-based approaches yield tangible gains in forecasting accuracy and parameter recovery for KRW-centred exchange-rate systems.
Table 1.
Results of simulating the KRW exchange rate for Design and .
Table 1 reports the simulation results for the two data-generating designs, focusing on both forecasting performance, measured by RMSFE, and estimation accuracy, summarised by MEE. Standard errors for the estimation errors are shown in parentheses where applicable. Together, these metrics provide complementary evidence on how alternative modelling strategies perform in high-dimensional KRW exchange-rate systems under different dependence structures and sample sizes. Under Design , which reflects localised interaction patterns consistent with strong regional and trade-based linkages in the Korean foreign-exchange market, several regularities emerge. Across all methods, RMSFE declines monotonically as the time dimension increases, indicating that longer samples systematically improve predictive accuracy. This pattern is consistent with the stable yet persistent dynamics observed in KRW bilateral exchange rates. The spatial-temporal autoregressive benchmark (ST-AR) achieves the lowest RMSFE in this setting. This outcome is expected, as the imposed interaction structure coincides with the true data-generating process and requires estimation of only a small number of parameters. Notably, all three variants of SPLASH deliver forecasting performance that is very close to this benchmark. The small gap in RMSFE indicates that the efficiency loss from estimating the interaction structure in a fully data-driven manner is limited, even in moderate samples. This result highlights the ability of structured sparsity to recover economically meaningful exchange-rate linkages without relying on prior specification of spatial weights. Differences across the three SPLASH implementations are modest. Group-level regularisation provides slight gains only in the most demanding configuration, where the cross-sectional dimension is large and the time dimension is short. Outside this case, the relative performance of the SPLASH variants is highly stable. The LaSo estimator also performs well in Design A, reflecting the fact that its spatial weight matrix already embeds the correct interaction pattern. However, its forecasting accuracy deteriorates when sample sizes are small, suggesting sensitivity to penalty selection and initialisation. This sensitivity is particularly relevant for KRW exchange rates, where short-sample instability often arises during periods of global financial stress. The generalised Yule–Walker estimators perform substantially worse. In small samples, the data-driven bandwidth selection frequently understates the true interaction range, leading to systematic underfitting and elevated forecast errors. Although the infeasible version that uses the true bandwidth improves estimation accuracy, its forecasting performance remains weak. Closer inspection indicates that this behaviour is driven by numerical instability when the smallest eigenvalue of the estimated matrix approaches zero. Since forecasts rely on the inverse of this matrix, small perturbations in estimation can translate into large forecast errors. The penalised VAR produces stable but comparatively less accurate forecasts, confirming that ignoring contemporaneous cross-currency interactions imposes a non-trivial cost in predictive performance.
Design represents a more challenging environment, characterised by broader and less localised dependence structures that better reflect complex global transmission channels affecting the KRW. In this setting, forecasting errors increase for all methods, underscoring the difficulty of recovering diffuse interaction patterns in high-dimensional exchange-rate systems. Despite this increased complexity, SPLASH continues to outperform the majority of benchmark models. Its advantage over methods based on fixed spatial weights becomes more pronounced, particularly as the cross-sectional dimension grows. This finding reflects the importance of allowing the data to determine the structure of exchange-rate interactions when the true dependence pattern deviates from simple nearest-neighbour relationships. The ST-AR and LaSo estimators exhibit notable deterioration in performance under Design B. Since both rely on pre-specified spatial weights aligned with Design , their structure becomes misspecified in this environment. As a result, forecasting errors increase sharply, especially in larger systems. The GMWY estimators again display substantial instability, with large estimation errors and weak forecasting accuracy. Increasing the sample size improves estimation precision but does not fully mitigate the adverse effects of bandwidth misalignment and numerical sensitivity. The penalised VAR remains stable across configurations but consistently underperforms models that explicitly account for contemporaneous exchange-rate spillovers. This pattern reinforces the view that purely temporal specifications are insufficient for capturing the network-driven dynamics that characterise KRW exchange-rate movements in globally integrated markets.
Taken together, the results in Table 1 demonstrate that explicitly modelling high-dimensional interaction structures yields substantial gains in both estimation and forecasting performance for KRW exchange rates. When the interaction pattern is simple and correctly specified, parsimonious spatial-temporal models perform well. However, when dependence structures become more complex and less localised, data-driven approaches based on structured sparsity offer clear advantages. These findings align closely with the empirical characteristics of the Korean foreign-exchange market, where exchange-rate dynamics are shaped by both regional proximity and broader global spillovers that evolve over time. While the numerical results in Table 1 establish the comparative advantages of modelling high-dimensional interaction structures, they do not directly reveal how such gains arise from the underlying contemporaneous dependence patterns. To complement the performance-based evidence, Figure 3 provides a structural visualisation of the KRW exchange-rate system by contrasting the true contemporaneous interaction matrix with its data-driven estimates. This comparison offers a transparent illustration of how economically ordered cross-currency linkages are embedded in the model and subsequently recovered under repeated sampling. By moving from aggregate forecast and estimation metrics to matrix-level representations, the figure clarifies the mechanism through which structured sparsity captures both localised and extended spillovers in the Korean foreign-exchange market. In doing so, it links the quantitative improvements documented in Table 1 to the underlying network structure that governs KRW exchange-rate dynamics.
Figure 3.
KRW exchange-rate simulation: (a) Results of the true KRW contemporaneous interaction matrix ; (b) Results of the average absolute value of the matrix is estimated under Monte Carlo.
Figure 3 provides a structural perspective on the simulation results by visualising the contemporaneous interaction matrix underlying the KRW exchange-rate system and its estimated counterpart. Panel (a) displays the true interaction matrix , constructed to reflect economically ordered cross-currency linkages that are consistent with Korea’s trade exposure, regional integration, and global financial connections. The concentration of non-zero entries along a limited number of diagonals highlights the presence of localised spillovers, while the gradual attenuation away from the main diagonal captures weaker interactions with economically more distant currencies. Panel (b) reports the average absolute values of the estimated interaction matrix obtained across Monte Carlo replications. Several features are noteworthy. First, the dominant diagonal patterns observed in the true matrix are clearly preserved in the estimated counterpart, indicating that the data-driven procedure successfully recovers the main channels of contemporaneous dependence. Second, coefficients outside the economically relevant bands are substantially attenuated, reflecting effective shrinkage of spurious interactions. This pattern is consistent with the role of group-level regularisation in isolating meaningful spillover structures while suppressing noise in high-dimensional settings. The close visual correspondence between panels (a) and (b) provides direct evidence that the structured sparsity framework captures the underlying organisation of the KRW exchange-rate network. Importantly, this recovery is achieved without imposing the interaction structure ex ante. Instead, the estimator reconstructs the dominant dependence patterns from the data, even in the presence of estimation noise and finite samples. The remaining dispersion in the estimated matrix reflects both unavoidable sampling variability and the deliberate allowance for weak, heterogeneous interactions that characterise globally integrated currency markets. Taken together, Figure 3 clarifies the mechanism behind the performance gains documented in Table 1. Accurate forecasting and low estimation error arise not merely from regularisation, but from the ability to recover the economically relevant architecture of contemporaneous spillovers. In the context of the Korean foreign-exchange market, this architecture is shaped by a combination of regional proximity and broader global transmission channels. The figure thus links the quantitative improvements in predictive accuracy to the successful identification of the network structure that governs KRW exchange-rate dynamics.
4.3. Empirical Analysis of KRW Exchange-Rate Dynamics
In this section, the SPLASH framework is applied to high-frequency exchange-rate data associated with the KRW. Section 4.1 provides a practical overview of the empirical workflow, outlining the key steps involved in data construction, preprocessing, and model implementation for high-dimensional currency systems. Section 4.2 then presents a concrete application, focusing on the prediction of daily bilateral KRW exchange-rate movements against a broad set of major trading-partner currencies.
4.3.1. Experimental Design
To facilitate the empirical application of the SPLASH modelling framework in an exchange-rate setting, this subsection outlines the main steps required to construct, preprocess, and analyse high-dimensional KRW exchange-rate data. The focus is on practical implementation using the dataset employed in this study and a MATLAB-based computational environment. The discussion is intended to provide clear guidance for applied researchers working with large panels of bilateral exchange rates, while remaining fully consistent with the modelling framework developed in the preceding sections. Step 1: Data collection: The analysis relies on daily bilateral exchange-rate series for the KRW against a broad set of major trading-partner currencies, as described in the empirical section of this paper. All exchange-rate series are obtained from standard financial data sources and correspond to the sample period considered in this study. After selecting the relevant currency pairs, the data are synchronised to a common trading calendar. Observations affected by market holidays, non-trading days, or data irregularities are carefully screened to ensure cross-currency comparability. This procedure yields a high-dimensional time series that captures Korea’s exposure to global and regional currency movements. Step 2: Data processing: The raw exchange-rate levels are transformed into daily returns or log differences in accordance with the empirical specification. The resulting series are arranged into a multivariate time series vector, where each component represents a specific KRW bilateral exchange rate observed over time. Missing observations may arise due to differences in trading calendars or temporary market disruptions. Such gaps are addressed using multivariate time-series imputation techniques that preserve the joint dependence structure across currencies. In addition, the presence of low-frequency movements or persistent seasonal patterns is examined. Direct implementation of model (1) or (10) on daily observations may inadequately capture low-frequency components embedded in exchange-rate movements. These persistent features are therefore examined independently and, when necessary, removed or explicitly modelled prior to the estimation stage. This preprocessing step removes low-frequency non-stationary components and ensures consistency with the stability conditions imposed in the spatio-temporal VAR framework. Step 3: Model implementation. Parameter estimation is carried out through a dedicated MATLAB routine that operationalises the SPLASH framework. This routine streamlines the principal elements of the estimation workflow, encompassing data-driven bandwidth determination, construction of band-restricted covariance estimates, evaluation of the quantities entering the generalised Yule–Walker relations, and calibration of regularisation parameters using a time-series cross-validation scheme, as outlined in Algorithm S1. The resulting sparsified coefficient matrices offer a clear and interpretable depiction of the dominant contemporaneous and dynamic linkages across KRW bilateral exchange rates. These estimates further enable the derivation of an implied reduced-form VAR system, which serves as a basis for out-of-sample predictive exercises and a deeper investigation of exchange-rate spillover effects within Korea’s foreign-exchange market.
4.3.2. Simulation Design and Implementation
Before turning to formal simulation outcomes, it is instructive to examine the low-frequency structure embedded in the KRW exchange-rate data. Exchange-rate movements often reflect not only high-frequency financial shocks but also systematic calendar-related patterns associated with global trading activity, macroeconomic cycles, and institutional market rhythms. Identifying such periodic components is essential, as unmodelled seasonality can distort both parameter estimation and predictive performance in high-dimensional dynamic systems. To this end, the aggregate behaviour of the KRW exchange-rate network is first analysed through its system-level average, allowing dominant cyclical features to be isolated prior to simulation analysis. Figure 4 summarises this preliminary assessment by documenting the presence of a pronounced annual component and illustrating how its removal alters the spectral properties of the series. This step provides a transparent justification for the subsequent simulation and modelling choices, ensuring that dynamic interactions are evaluated net of deterministic seasonal effects.
Figure 4.
KRW exchange-rate: (a) Results of Annual seasonality in KRW exchange-rate dynamics; (b) Results of Spectral density before vs. after removing annual Fourier term (q = 400).
Figure 4 provides a systematic characterisation of low-frequency dynamics in the KRW exchange-rate system by combining time-domain and frequency-domain evidence. Panel (a) illustrates the evolution of the system-level average of bilateral KRW exchange-rate movements together with its first-order Fourier approximation based on an annual cycle. The observed series exhibits recurrent fluctuations that are smooth and persistent over time, indicating the presence of a stable seasonal component rather than episodic or regime-specific behaviour. The fitted Fourier term closely tracks these low-frequency movements, suggesting that a single annual cycle captures a substantial share of the deterministic variation embedded in the aggregate exchange-rate dynamics. This pattern is consistent with the institutional and macroeconomic environment of the Korean foreign-exchange market, where calendar effects related to global trade flows, fiscal cycles, and synchronised financial activity tend to repeat at an annual frequency. Importantly, the seasonal component manifests at the system level, implying that it reflects common forces affecting multiple KRW bilateral exchange rates rather than idiosyncratic movements of individual currency pairs. Panel (b) complements this evidence by examining the spectral properties of the same aggregate series before and after removing the estimated annual Fourier component. Prior to detrending, the spectral density displays a pronounced peak at the frequency corresponding to a 365-day cycle, confirming the dominance of annual periodicity in the data. After subtracting the first-order Fourier term, this peak is largely eliminated, and the remaining spectrum becomes comparatively flat across frequencies. The absence of additional dominant peaks indicates that higher-order seasonal components contribute little incremental explanatory power. This finding supports the use of a parsimonious seasonal adjustment based on a single annual frequency and suggests that residual exchange-rate fluctuations are primarily driven by higher-frequency stochastic shocks rather than unmodelled deterministic cycles. Taken together, the two panels provide clear justification for removing the annual seasonal component prior to simulation and dynamic modelling. By isolating and filtering out deterministic low-frequency variation, the subsequent analysis can focus on the intrinsic contemporaneous and intertemporal dependence structures that govern KRW exchange-rate interactions. This preprocessing step ensures that estimated spillover effects and forecasting results reflect genuine market dynamics rather than predictable calendar-driven movements, thereby strengthening the economic interpretation and empirical reliability of the simulation outcomes that follow.
A rolling-window framework is employed to evaluate the forecasting performance of the SPLASH estimator in the context of KRW exchange-rate dynamics. Guided by the preceding seasonality analysis, the data-generating process is specified as , , , where denotes an -dimensional vector of ones. Consistent with the spectral evidence documented earlier, the specification adopts , while recognising that alternative datasets may require higher-order Fourier components. Under this formulation, each exchange-rate node is characterised by its own mean level and a common seasonal pattern capturing system-wide periodic fluctuations. Each rolling window covers approximately two years of trading-day observations drawn from the daily KRW exchange-rate sample spanning 2019–2023. This rolling scheme generates a sequence of one-step-ahead forecasts over the full evaluation period, ensuring that each prediction is based solely on information available at the time of estimation. For each window, the forecasting exercise follows a four-stage procedure. This analysis proceeds in three sequential stages. In the first step, the deterministic term is isolated and removed, yielding an adjusted series that is free of seasonal effects. The second step applies the estimation procedure to this adjusted trading-day series in order to recover both the model parameters and the associated tuning constants. In the final step, one-period-ahead predictions are generated separately for the stochastic component and for the deterministic seasonal component, which are subsequently combined for forecasting purposes. Finally, these components are recombined to obtain forecasts of the KRW exchange-rate outcomes observed on the trading day immediately following each rolling window.
The same classes of estimators as those considered in the simulation analysis are employed in the empirical forecasting exercise. Specifically, the implementations include SPLASH, SPLASH, and SPLASH. Given the cross-currency dimension of the KRW exchange-rate system, the unrestricted specification would involve a large number of parameters. To ensure identifiability, consistent with Condition 3, both the contemporaneous interaction matrix and the autoregressive matrix are constrained by imposing a banded structure, such that for . In line with the simulation design, the regularisation parameter is selected as , where the multiplicative factor is determined through a preliminary set of out-of-sample forecasts. In the absence of prior information regarding the structure of cross-currency interactions, the ST-AR and LaSo benchmark models are implemented using two alternative weighting schemes. The first adopts a nearest-neighbour specification consistent with the ordering strategy employed earlier, while the second relies on a normalised inverse-distance weighting matrix , where each element reflects the inverse economic distance between currency pairs iii and . In the empirical implementation, the GMWY procedure is carried out using a fixed bandwidth choice of , a specification that delivers the most reliable forecasting behaviour in the present exercise. For the LaSo and PVAR benchmark methods, tuning parameters are selected using the identical time-series cross-validation scheme outlined in Section 4.1, thereby maintaining a consistent basis for comparison across all forecasting strategies considered. Predictive performance is assessed through a set of three complementary indicators. These include: (i) the mean forecast loss computed relative to the PVAR reference model, (ii) the count of bilateral exchange−rate series for which a given approach achieves superior predictive accuracy compared with the PVAR benchmark (reported as the number of wins), and (iii) inclusion in the Model Confidence Set (MCS) constructed according to Hansen et al. (2011) [61] using a 10% significance threshold. All evaluation metrics are calculated under two alternative loss specifications for forecast errors, namely MSFE and MRFE. Specifically, letting denote the one-step-ahead prediction error generated by method jjj for the iii-th KRW bilateral exchange rate at forecast origin , the associated loss functions are defined as follows.
In Equation (17), represent the longest prediction window considered. The MRFE criterion is employed to dampen the impact of sporadic large fluctuations in exchange-rate returns and to guard against numerical sensitivity that may arise in the implementation of certain benchmark forecasting methods. Such abrupt fluctuations are a common feature of foreign-exchange markets and may disproportionately affect loss measures based solely on squared errors. To provide a balanced evaluation of forecasting performance, Table 2 reports both RMSFE and RMRFE, each computed with respect to the PVAR benchmark.
Table 2.
Results of forecast performance of alternative methods for KRW exchange-rate data.
Table 2 summarises the out-of-sample forecasting performance of alternative modelling approaches applied to high-dimensional KRW exchange-rate data. Performance is evaluated relative to the penalised reduced-form VAR benchmark using both RMSFE and RMRFE, together with complementary information on the number of series for which each method outperforms the benchmark and membership in the MCS. Several clear patterns emerge. Across all metrics, the SPLASH family consistently delivers the strongest forecasting performance. All three variants achieve RMSFE and RMRFE values well below unity and outperform the benchmark for a large majority of KRW bilateral exchange rates. Among them, the intermediate specification that balances group-level and individual sparsity exhibits the most stable dominance, achieving the lowest average losses and the highest number of wins. This result indicates that KRW exchange-rate dynamics are best characterised by a combination of clustered spillovers and idiosyncratic bilateral effects, rather than by purely global or purely pair-specific dependence. The superiority of SPLASH is even more pronounced when forecast accuracy is assessed using the robust loss measure. The improvement in RMRFE relative to RMSFE suggests that explicitly modelling contemporaneous cross-currency interactions is particularly valuable in mitigating the impact of extreme exchange-rate movements. This finding is consistent with the empirical properties of the Korean foreign-exchange market, where global shocks, geopolitical events, and shifts in international risk sentiment can induce abrupt and uneven adjustments across currency pairs. Spatial–temporal autoregressive benchmarks retain some explanatory power but perform noticeably worse than SPLASH. Both specifications remain within the Model Confidence Set, yet their higher forecast losses reflect the limitations of relying on fixed interaction structures. In a market as globally integrated as Korea’s, pre-specified spatial weights are unlikely to capture the full range of evolving cross-currency linkages, especially during periods of heightened volatility. The LaSo estimators display mixed performance. While the inverse-distance specification remains competitive for a subset of exchange-rate series, the nearest-neighbour variant fails to enter the confidence set. This divergence highlights the sensitivity of sparse deviation models to the initial choice of spatial weights. When the imposed structure does not align well with the true dependence pattern, regularisation alone is insufficient to restore forecasting accuracy.
The generalised Yule–Walker estimator performs poorly across all criteria. Both RMSFE and RMRFE substantially exceed unity, and the number of wins is minimal. This outcome reflects the estimator’s vulnerability to bandwidth selection errors and numerical instability in high-dimensional systems. Such weaknesses are particularly problematic in exchange-rate applications, where contemporaneous interactions and near-collinearity among currencies are common. As expected, the reduced-form PVAR delivers stable but inferior forecasts. Its role as a benchmark underscores the cost of ignoring contemporaneous cross-currency spillovers. While lagged dynamics capture part of KRW exchange-rate persistence, they fail to account for instantaneous transmission mechanisms that are central to modern foreign-exchange markets. Taken together, the evidence in Table 2 demonstrates that forecasting KRW exchange rates benefits substantially from models that explicitly recover high-dimensional interaction networks in a data-driven manner. The consistent dominance of SPLASH across loss functions, series-level comparisons, and statistical confidence sets underscores the importance of jointly modelling contemporaneous and dynamic spillovers. These results reinforce the view that Korea’s exchange-rate dynamics are shaped by a complex and evolving network of global and regional linkages, which cannot be adequately captured by low-dimensional or rigidly structured models.
Figure 5 provides a visual characterisation of the sparsity structure underlying the estimated contemporaneous interaction matrix for KRW bilateral exchange rates, based on rolling-window estimation over the period 2019–2023. The analysis focuses on the SPLASH specification, which balances group-level and individual-level sparsity and therefore offers a flexible representation of cross-currency dependence in a globally integrated foreign-exchange market. Panel (a) displays the window-averaged absolute magnitudes of the estimated interaction coefficients. A clear concentration of large values emerges along a limited set of diagonals close to the main diagonal, indicating that contemporaneous spillovers are primarily structured by economic proximity among KRW bilateral exchange rates. These diagonals correspond to clusters of currencies that are closely linked through trade exposure, regional integration, or shared sensitivity to global financial requirements. Interactions located further away from the main diagonal exhibit substantially smaller magnitudes, suggesting that instantaneous spillovers across economically distant currency pairs are comparatively weak on average. Panel (b) complements this evidence by reporting the selection frequency of each interaction, defined as the proportion of rolling windows in which the corresponding coefficient is estimated to be nonzero. The heat map reveals that interactions associated with the dominant diagonals are selected with high frequency, often across a majority of rolling windows. This persistence indicates that these spillovers represent stable and recurrent features of the KRW exchange-rate system rather than transient artefacts driven by short-lived market episodes. In contrast, off-diagonal interactions away from the economically relevant bands are selected infrequently, consistent with the presence of effective shrinkage that suppresses spurious or episodic linkages in high-dimensional settings.
Figure 5.
KRW exchange-rate application: (a) Results of average absolute entries of across rolling windows; (b) Results of selection frequency: ; (c) Results of focal node KEW: links active in at least 20% of rolling windows.
Panel (c) provides a more interpretable illustration by focusing on a representative focal KRW bilateral exchange rate and visualising the subset of contemporaneous interactions that remain active in at least 20% of the rolling windows. The resulting network highlights a small number of economically meaningful connections, with link thickness reflecting the average estimated magnitude of the interaction. Strong links tend to connect the focal rate to currencies that play a central role in Korea’s external trade and financial relationships, while weaker links capture more diffuse global spillovers. The absence of dense connections outside this core set underscores the effectiveness of structured sparsity in isolating the most relevant contemporaneous transmission channels. Taken together, the three panels offer a coherent depiction of how high-dimensional dependence in KRW exchange rates is organised and recovered empirically. The visual patterns reinforce the quantitative findings reported earlier by showing that forecasting and estimation gains arise from identifying a sparse but economically structured network of contemporaneous interactions. In the context of the Korean foreign-exchange market, this structure reflects the coexistence of regional proximity effects and broader global linkages, both of which evolve over time yet remain sufficiently stable to be captured through rolling-window estimation.
5. Conclusions
This study examined the complex dynamics of the KRW through a high-dimensional framework that captures both contemporaneous and intertemporal linkages among 36 bilateral exchange rates. By integrating the generalised Yule–Walker equations with structured penalisation, the sparse spatio-temporal vector autoregressive (SPLASH) model provided a tractable and data-driven approach to uncovering the underlying dependence structure across currencies. The framework demonstrated that Korea’s exchange-rate network is organised around a sparse yet economically coherent set of interactions, with strong spillovers concentrated among currencies closely connected through trade intensity and financial integration. This configuration reflects a hybrid structure of regional clustering and global connectivity, characterising how shocks in major markets propagate through the Korean foreign-exchange system. Simulation and empirical analyses consistently confirmed the robustness of the proposed approach. The SPLASH estimator achieved marked improvements in forecasting accuracy relative to standard spatial-temporal and penalised VAR models, particularly under conditions of volatility and heterogeneity. These results emphasise the methodological value of integrating sparsity-based regularisation with spatio-temporal time-series modelling in high-dimensional environments. Beyond predictive gains, the findings reveal that exchange-rate dependencies are neither uniformly distributed nor random; instead, they follow interpretable network geometries that align with Korea’s trade and capital flows. This insight deepens the understanding of cross-market linkages and offers a powerful analytical foundation for studying similar high-dimensional systems in global finance.
This paper yields several general insights into the behaviour of high-dimensional exchange-rate markets. Exchange-rate dynamics are shaped by sparse yet persistent network structures rather than by diffuse or purely idiosyncratic interactions. In the case of the Korean won, contemporaneous spillovers concentrate among currencies linked through trade and financial integration, while broader global shocks propagate along a limited number of stable transmission channels. This configuration reveals a structured form of dependence in which regional clustering coexists with selective global connectivity, a pattern that is likely to characterise other open and highly integrated currency systems. These findings also expose fundamental limitations of traditional exchange-rate models. Approaches that rely exclusively on lagged dynamics or impose fixed interaction structures are unable to capture instantaneous cross-currency transmission and tend to understate the role of network effects. As dependence patterns evolve during periods of heightened uncertainty or global stress, such models lack the flexibility needed to track shifts in spillover intensity and direction. By contrast, a network-based representation allows exchange-rate interactions to be interpreted as an adaptive system rather than as a collection of isolated bilateral processes. From a policy and risk-management perspective, these insights underscore the value of viewing exchange rates as components of a dynamic network. Monitoring stable spillover pathways provides a more realistic basis for assessing external vulnerability and systemic risk, particularly for small open economies exposed to global financial cycles. Network-oriented surveillance can help identify clusters of currencies that jointly amplify external shocks, while data-driven forecasting tools grounded in high-dimensional modelling offer more reliable guidance for managing currency risk than approaches based solely on pairwise or low-dimensional forecasts.
Beyond its analytical contribution, the framework has clear practical relevance for financial institutions and central banks, including authorities such as the Bank of Korea. By providing a rolling, data-driven representation of contemporaneous exchange-rate networks, the model can support real-time monitoring of shock transmission risk across currencies. Persistent spillover pathways identified in the network offer an operational basis for distinguishing structural vulnerabilities from short-lived market noise. For policy institutions, such information can complement existing macro-financial surveillance tools by highlighting which external shocks are most likely to propagate rapidly through the exchange-rate system. For financial institutions, the same network structure can be integrated into internal forecasting and stress-testing exercises, improving scenario analysis and risk allocation by accounting explicitly for cross-currency interdependence rather than treating exchange rates in isolation. Looking ahead, several extensions arise naturally from the proposed framework. One direction involves allowing for higher-order temporal dynamics, which would enable the model to capture delayed and multi-stage transmission patterns in exchange-rate systems. Relatedly, permitting time-varying network structures or regime-dependent sparsity would improve the ability to track abrupt structural shifts, especially during periods of financial stress. Another promising avenue concerns alternative regularisation schemes, including adaptive or debiased penalties, which could better accommodate heterogeneity while enabling valid statistical inference on spillover effects. Beyond foreign exchange markets, the framework is readily applicable to other interconnected financial systems, such as equity markets, sovereign bond networks, and cross-asset risk transmission structures. Incorporating macro-financial fundamentals and global risk indicators into these settings could further bridge structural and statistical representations of financial dynamics. Together, these extensions underscore the flexibility of the approach and point to a broader role for sparse spatio-temporal modelling in understanding and forecasting complex financial networks. An additional direction concerns the integration of the proposed network-based framework with more advanced hybrid time-series models. Recent developments in nonlinear and regime-switching specifications—such as Periodic Bilinear GARCH or double-switching ARMA models—highlight the importance of capturing time-varying volatility, asymmetry, and structural breaks in exchange-rate dynamics. The results of this study suggest that such models could be enriched by incorporating data-driven network structures, allowing switching behaviour or volatility dynamics to depend explicitly on evolving cross-currency linkages. In this sense, the present framework can serve as a modular backbone for future hybrid models that jointly address network dependence, nonlinear dynamics, and regime shifts in high-dimensional exchange-rate systems.
Supplementary Materials
The following supporting information can be downloaded at: https://www.mdpi.com/article/10.3390/math14030482/s1.
Author Contributions
Conceptualization, X.H. and Y.H.; methodology, X.H. and Y.H.; software, X.H.; validation, X.H.; formal analysis, X.H.; investigation, X.H.; data curation, X.H.; writing—original draft preparation, X.H.; writing—review and editing, Y.H.; visualization, X.H. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Data Availability Statement
The original data presented in this study are included in this article. Further inquiries can be directed to the corresponding author.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Taly, I. Study on Return and Volatility Spillover Effects among Stock, CDS, and Foreign Exchange Markets in Korea. East Asian Econ. Rev. 2015, 19, 275–322. [Google Scholar] [CrossRef] [Scilit]
- Kim, B.-H.; Kim, H.; Lee, B.-S. Spillover Effects of the US Financial Crisis on Financial Markets in Emerging Asian Countries. Int. Rev. Econ. Financ. 2015, 39, 192–210. [Google Scholar] [CrossRef] [Scilit]
- Plantin, G.; Shin, H.S. Exchange Rates and Monetary Spillovers. Theor. Econ. 2018, 13, 637–666. [Google Scholar] [CrossRef] [Scilit]
- Lee, S.; Kim, Y.M. Effect of Foreign Exchange Intervention: The Case of Korea. Pac. Econ. Rev. 2020, 25, 641–659. [Google Scholar] [CrossRef] [Scilit]
- Son, B.; Lee, Y.; Park, S.; Lee, J. Forecasting Global Stock Market Volatility: The Impact of Volatility Spillover Index in Spatial-temporal Graph-based Model. J. Forecast. 2023, 42, 1539–1559. [Google Scholar] [CrossRef] [Scilit]
- Kirkulak Uludag, B.; Khurshid, M. Volatility Spillover from the Chinese Stock Market to E7 and G7 Stock Markets. J. Econ. Stud. 2019, 46, 90–105. [Google Scholar] [CrossRef] [Scilit]
- Chen, M.; Li, N.; Zheng, L.; Huang, D.; Wu, B. Dynamic Correlation of Market Connectivity, Risk Spillover and Abnormal Volatility in Stock Price. Phys. A Stat. Mech. Appl. 2022, 587, 126506. [Google Scholar] [CrossRef] [Scilit]
- Fernández-Rodríguez, F.; Sosvilla-Rivero, S. Volatility Transmission between Stock and Foreign Exchange Markets: A Connectedness Analysis. Appl. Econ. 2020, 52, 2096–2108. [Google Scholar] [CrossRef] [Scilit]
- Wang, P.; Li, Y.; Liu, X. Asymmetric Spillover between Economic Policy Uncertainty and Exchange Rate Volatility: A Global Network Connectedness Perspective. PLoS ONE 2023, 18, e0279729. [Google Scholar] [CrossRef] [Scilit]
- Boakye, R.O.; Mensah, L.K.; Kang, S.H.; Osei, K.A. Foreign Exchange Market Return Spillovers and Connectedness among African Countries. Int. Rev. Financ. Anal. 2023, 86, 102505. [Google Scholar] [CrossRef] [Scilit]
- Chan, J.C.C.; Eisenstat, E. Bayesian Model Comparison for Time-varying Parameter VARs with Stochastic Volatility. J. Appl. Econom. 2018, 33, 509–532. [Google Scholar] [CrossRef] [Scilit]
- Huber, F.; Feldkircher, M. Adaptive Shrinkage in Bayesian Vector Autoregressive Models. J. Bus. Econ. Stat. 2019, 37, 27–39. [Google Scholar] [CrossRef] [Scilit]
- Barigozzi, M.; Hallin, M. A Network Analysis of the Volatility of High Dimensional Financial Series. J. R. Stat. Soc. Ser. C Appl. Stat. 2017, 66, 581–605. [Google Scholar] [CrossRef] [Scilit]
- Barigozzi, M.; Brownlees, C. NETS: Network Estimation for Time Series. J. Appl. Econom. 2019, 34, 347–364. [Google Scholar] [CrossRef] [Scilit]
- Krohn, I.; Sushko, V. FX Spot and Swap Market Liquidity Spillovers. J. Int. Money Financ. 2022, 120, 102476. [Google Scholar] [CrossRef] [Scilit]
- Cespa, G.; Gargano, A.; Riddiough, S.J.; Sarno, L. Foreign Exchange Volume. Rev. Financ. Stud. 2022, 35, 2386–2427. [Google Scholar] [CrossRef] [Scilit]
- Chen, W.-J.; Yao, J.-J.; Shao, Y.-H. Volatility Forecasting Using Deep Neural Network with Time-Series Feature Embedding. Econ. Res.-Ekon. Istraživanja 2023, 36, 1377–1401. [Google Scholar] [CrossRef] [Scilit]
- Ahelegbey, D.F.; Giudici, P. NetVIX—A Network Volatility Index of Financial Markets. Phys. A Stat. Mech. Appl. 2022, 594, 127017. [Google Scholar] [CrossRef] [Scilit]
- Gaskin, T.; Pavliotis, G.A.; Girolami, M. Inferring Networks from Time Series: A Neural Approach. PNAS Nexus 2024, 3, pgae063. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Bräuning, F.; Sheremirov, V. The Transmission Mechanisms of International Business Cycles: International Trade and the Foreign Effects of US Monetary Policy. IMF Econ. Rev. 2023, 71, 300–325. [Google Scholar] [CrossRef] [Scilit]
- Camara, S.; Christiano, L.; Dalgıc, H. The International Monetary Transmission Mechanism. NBER Macroecon. Annu. 2025, 39, 65–140. [Google Scholar] [CrossRef] [Scilit]
- Hung, N.T. Spillover Effects Between Stock Prices and Exchange Rates for the Central and Eastern European Countries. Glob. Bus. Rev. 2022, 23, 259–286. [Google Scholar] [CrossRef] [Scilit]
- Guru, B.K.; Yadav, I.S. Stock Market Integration and Volatility Spillovers: New Evidence from Asia–Pacific and European Markets. J. Risk Financ. 2023, 24, 186–211. [Google Scholar] [CrossRef] [Scilit]
- Shen, M.-L.; Lee, C.-F.; Liu, H.-H.; Chang, P.-Y.; Yang, C.-H. An Effective Hybrid Approach for Forecasting Currency Exchange Rates. Sustainability 2021, 13, 2761. [Google Scholar] [CrossRef] [Scilit]
- Ullah, U.; Huang, Z. Forecasting Currency Exchange Rate through a Hybrid Time Series Analysis. IEEE Trans. Consum. Electron. 2025, 71, 6027–6040. [Google Scholar] [CrossRef] [Scilit]
- Cavicchioli, M.; Ghezal, A.; Zemmouri, I. (Bi)spectral analysis of Markov switching bilinear time series. Stat. Methods Appl. 2025, 1–30. [Google Scholar] [CrossRef] [Scilit]
- Alraddadi, R. The logTG-SV model: A threshold-based volatility framework with logarithmic shocks for exchange rate dynamics. AIMS Math. 2025, 10, 19495–19511. [Google Scholar] [CrossRef] [Scilit]
- Habib, M.M.; Bützer, S.; Stracca, L. Global Exchange Rate Configurations: Do Oil Shocks Matter? IMF Econ. Rev. 2016, 64, 443–470. [Google Scholar] [CrossRef] [Scilit]
- Gil-Alana, L.A.; Carcel, H. A Fractional Cointegration Var Analysis of Exchange Rate Dynamics. N. Am. J. Econ. Financ. 2020, 51, 100848. [Google Scholar] [CrossRef] [Scilit]
- Le, C.; Nguyen, H.; Vo, D. Global Liquidity Spillovers in the Asia–Pacific Region: Policy-Driven versus Market-Driven Effects. Empir. Econ. 2024, 67, 1091–1113. [Google Scholar] [CrossRef] [Scilit]
- Hauzenberger, N.; Huber, F. Model Instability in Predictive Exchange Rate Regressions. J. Forecast. 2020, 39, 168–186. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Dou, B.; Parrella, M.L.; Yao, Q. Generalized Yule–Walker Estimation for Spatio-Temporal Models with Unknown Diagonal Coefficients. J. Econom. 2016, 194, 369–382. [Google Scholar] [CrossRef] [Scilit]
- Hou, L.; Jin, B.; Wu, Y. Estimation and Variable Selection for High-Dimensional Spatial Dynamic Panel Data Models. J. Econom. 2024, 238, 105605. [Google Scholar] [CrossRef] [Scilit]
- Pu, D.; Fang, K.; Lan, W.; Yu, J.; Zhang, Q. Reduced Rank Spatio-Temporal Models. J. Bus. Econ. Stat. 2025, 43, 98–109. [Google Scholar] [CrossRef] [Scilit]
- Giordano, F.; Niglio, M.; Parrella, M.L. Testing Spatial Dynamic Panel Data Models with Heterogeneous Spatial and Regression Coefficients. J. Time Ser. Anal. 2024, 45, 771–799. [Google Scholar] [CrossRef] [Scilit]
- Feo, G.; Giordano, F.; Milito, S.; Niglio, M.; Parrella, M.L. Clustering and Classification of Spatio-Temporal Data Using Spatial Dynamic Panel Data Models. Adv. Data Anal. Classif. 2025, 19, 387–435. [Google Scholar] [CrossRef] [Scilit]
- Badinger, H.; Egger, P. Fixed Effects and Random Effects Estimation of Higher-Order Spatial Autoregressive Models with Spatial Autoregressive and Heteroscedastic Disturbances. Spat. Econ. Anal. 2015, 10, 11–35. [Google Scholar] [CrossRef] [Scilit]
- Li, T.; Guo, Y. Penalized Profile Quasi-Maximum Likelihood Method of Partially Linear Spatial Autoregressive Model. J. Stat. Comput. Simul. 2020, 90, 2705–2740. [Google Scholar] [CrossRef] [Scilit]
- Qiu, F.; Ding, H.; Hu, J. Asymptotic Properties of Quasi-Maximum Likelihood Estimators for Heterogeneous Spatial Autoregressive Models. Symmetry 2022, 14, 1894. [Google Scholar] [CrossRef] [Scilit]
- Kock, A.B.; Pedersen, R.S.; Sørensen, J.R.-V. Data-Driven Tuning Parameter Selection for High-Dimensional Vector Autoregressions. J. Am. Stat. Assoc. 2025, 1–14. [Google Scholar] [CrossRef] [Scilit]
- Zheng, Y. An Interpretable and Efficient Infinite-Order Vector Autoregressive Model for High-Dimensional Time Series. J. Am. Stat. Assoc. 2025, 120, 212–225. [Google Scholar] [CrossRef] [Scilit]
- Krisztin, T.; Piribauer, P. A Bayesian Approach for the Estimation of Weight Matrices in Spatial Autoregressive Models. Spat. Econ. Anal. 2023, 18, 44–63. [Google Scholar] [CrossRef] [Scilit]
- Hsu, N.-J.; Huang, H.-C.; Tsay, R.S. Matrix Autoregressive Spatio-Temporal Models. J. Comput. Graph. Stat. 2021, 30, 1143–1155. [Google Scholar] [CrossRef] [Scilit]
- Parrella, M.L.; Albano, G.; Perna, C.; La Rocca, M. Bootstrap joint prediction regions for sequences of missing values in spatio-temporal datasets. Comput. Stat. 2021, 36, 2917–2938. [Google Scholar] [CrossRef] [Scilit]
- Han, X.; Lee, L.-F. Bayesian Analysis of Spatial Panel Autoregressive Models with Time-Varying Endogenous Spatial Weight Matrices, Common Factors, and Random Coefficients. J. Bus. Econ. Stat. 2016, 34, 642–660. [Google Scholar] [CrossRef] [Scilit]
- Tugnait, J.K. Sparse-Group Lasso for Graph Learning from Multi-Attribute Data. IEEE Trans. Signal Process. 2021, 69, 1771–1786. [Google Scholar] [CrossRef] [Scilit]
- Sun, Y.; Malikov, E. Estimation and Inference in Functional-Coefficient Spatial Autoregressive Panel Data Models with Fixed Effects. J. Econom. 2018, 203, 359–378. [Google Scholar] [CrossRef] [Scilit]
- Mesters, G.; Koopman, S.J. Generalized dynamic panel data models with random effects for cross-section and time. J. Econom. 2014, 180, 127–140. [Google Scholar] [CrossRef] [Scilit]
- Liu, J.; Wonka, P.; Ye, J. A multi-stage framework for Dantzig selector and Lasso. J. Mach. Learn. Res. 2012, 13, 1189–1219. [Google Scholar]
- Kock, A.B.; Callot, L. Oracle Inequalities for High Dimensional Vector Autoregressions. J. Econom. 2015, 186, 325–344. [Google Scholar] [CrossRef] [Scilit]
- Medeiros, M.C.; Mendes, E.F. ℓ1-Regularization of High-Dimensional Time-Series Models with Non-Gaussian and Heteroskedastic Errors. J. Econom. 2016, 191, 255–271. [Google Scholar] [CrossRef] [Scilit]
- Zou, H. The Adaptive Lasso and Its Oracle Properties. J. Am. Stat. Assoc. 2006, 101, 1418–1429. [Google Scholar] [CrossRef] [Scilit]
- Knight, K.; Fu, W. Asymptotics for Lasso-Type Estimators. Ann. Stat. 2000, 28, 1356–1378. [Google Scholar] [CrossRef] [Scilit]
- Zhang, C.-H.; Zhang, S.S. Confidence Intervals for Low Dimensional Parameters in High Dimensional Linear Models. J. R. Stat. Soc. Ser. B Stat. Methodol. 2014, 76, 217–242. [Google Scholar] [CrossRef] [Scilit]
- Ma, Y.; Guo, S.; Wang, H. Sparse Spatio-Temporal Autoregressions by Profiling and Bagging. J. Econom. 2023, 232, 132–147. [Google Scholar] [CrossRef] [Scilit]
- Okui, R. Asymptotically Unbiased Estimation of Autocovariances and Autocorrelations with Long Panel Data. Econom. Theory 2010, 26, 1263–1304. [Google Scholar] [CrossRef] [Scilit]
- Yu, J.; De Jong, R.; Lee, L. Quasi-Maximum Likelihood Estimators for Spatial Dynamic Panel Data with Fixed Effects When Both n and T Are Large. J. Econom. 2008, 146, 118–134. [Google Scholar] [CrossRef] [Scilit]
- Lam, C.; Souza, P.C.L. Estimation and Selection of Spatial Weight Matrix in a Spatial Lag Model. J. Bus. Econ. Stat. 2020, 38, 693–710. [Google Scholar] [CrossRef] [Scilit]
- Masini, R.P.; Medeiros, M.C.; Mendes, E.F. Regularized Estimation of High-dimensional Vector Autoregressions with Weakly Dependent Innovations. J. Time Ser. Anal. 2022, 43, 532–557. [Google Scholar] [CrossRef] [Scilit]
- Hyndman, R.J.; Athanasopoulos, G. Forecasting: Principles and Practice; OTexts: Waterloo, ON, Canada, 2018. [Google Scholar]
- Hansen, P.R.; Lunde, A.; Nason, J.M. The model confidence set. Econometrica 2011, 79, 453–497. [Google Scholar] [CrossRef] [Scilit]
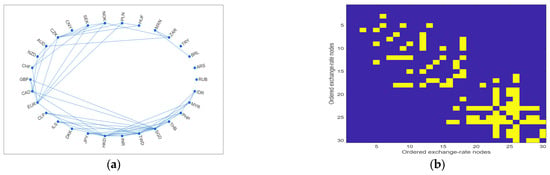
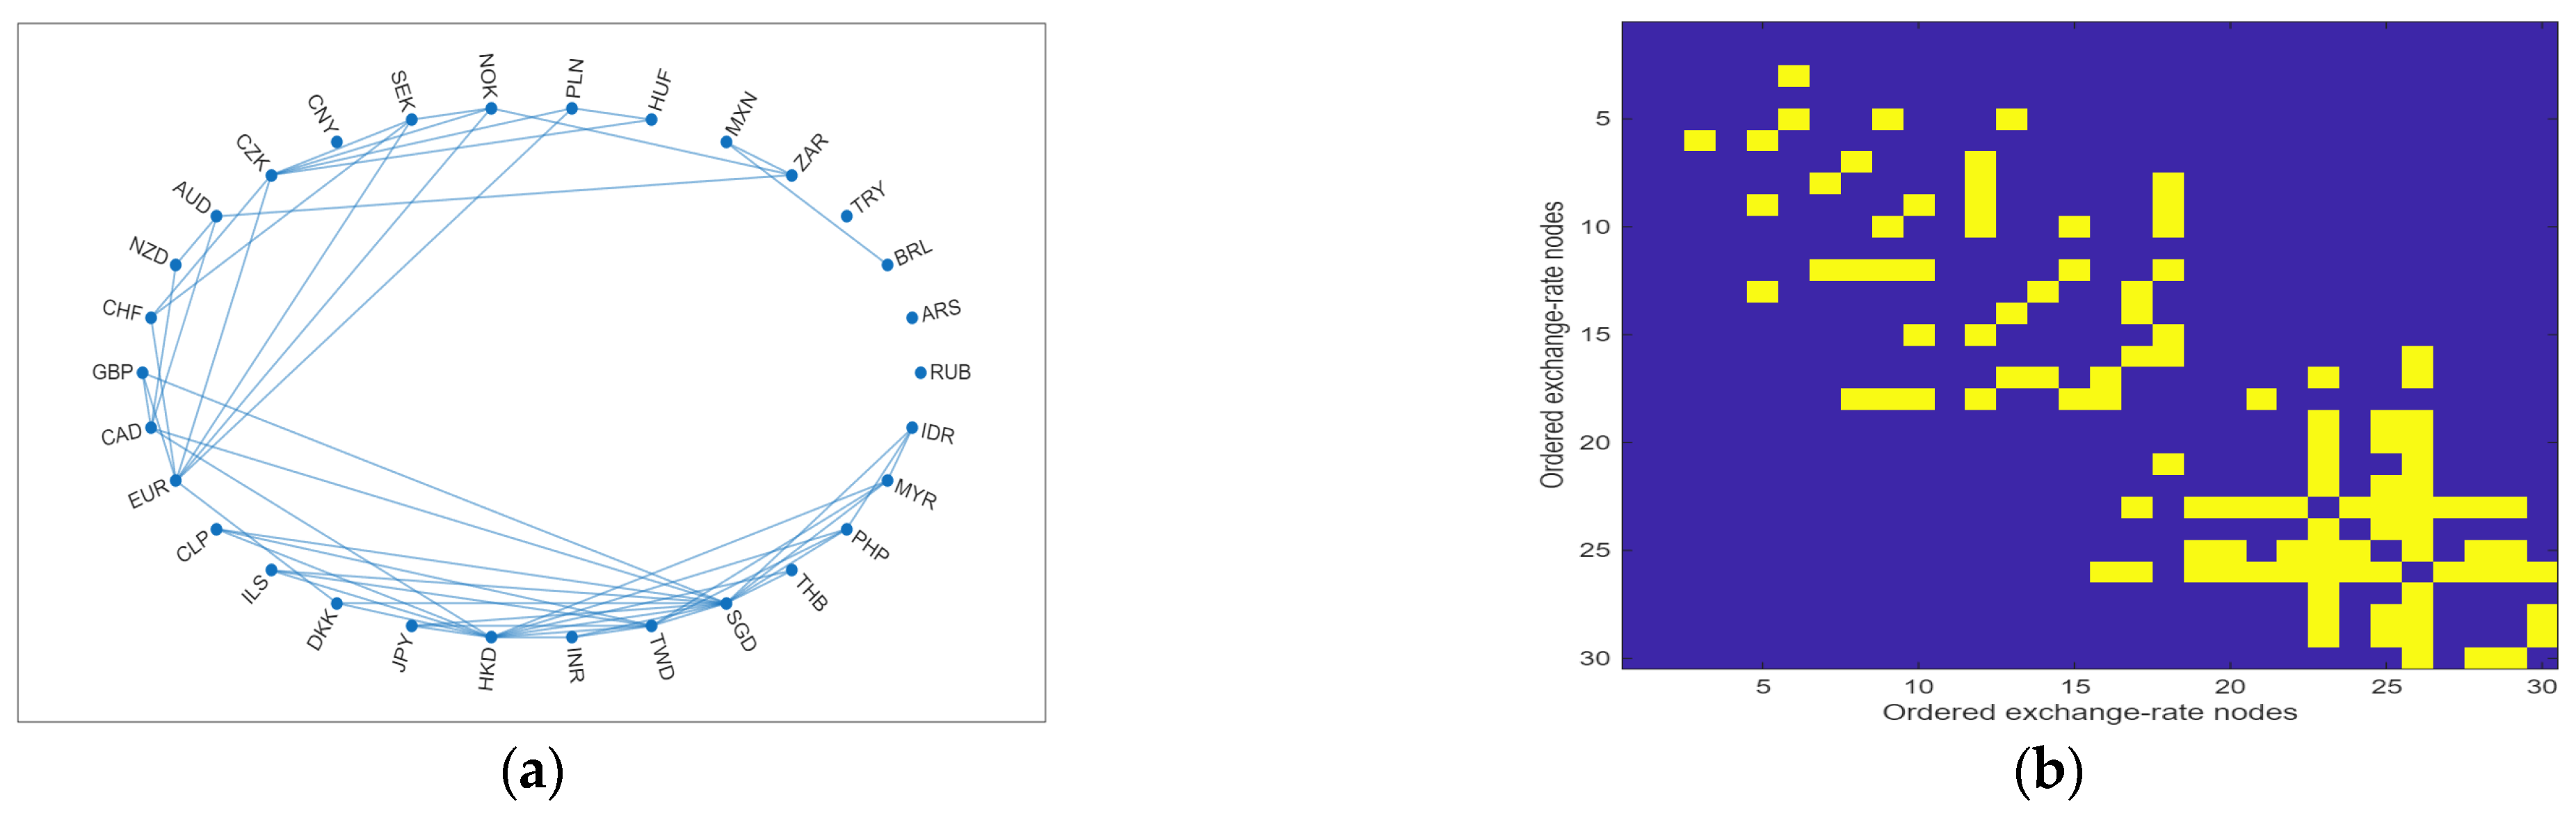
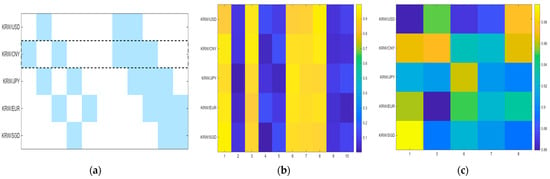
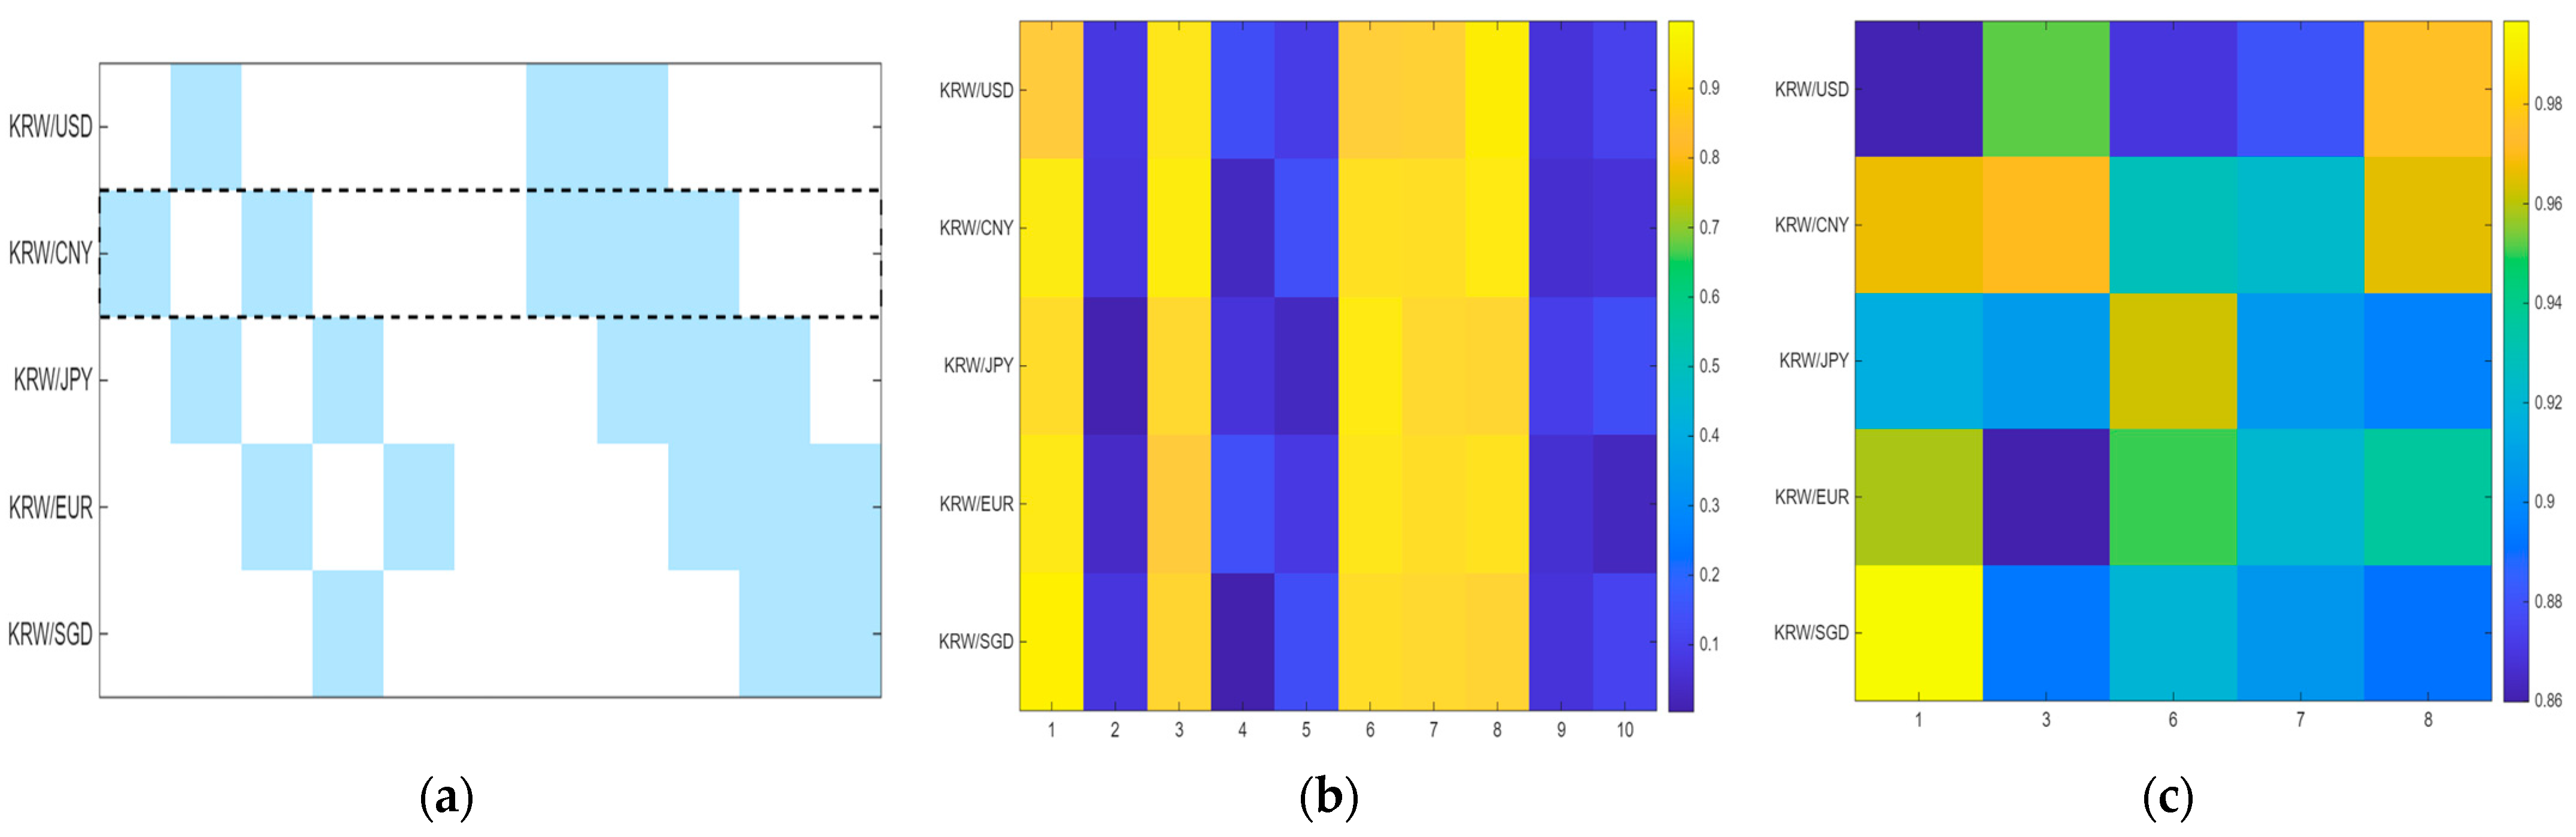
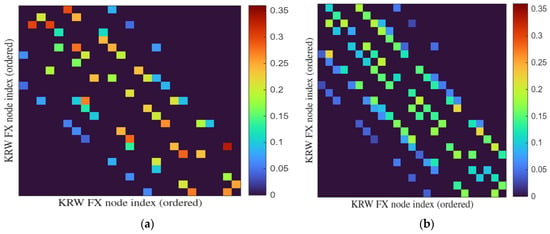
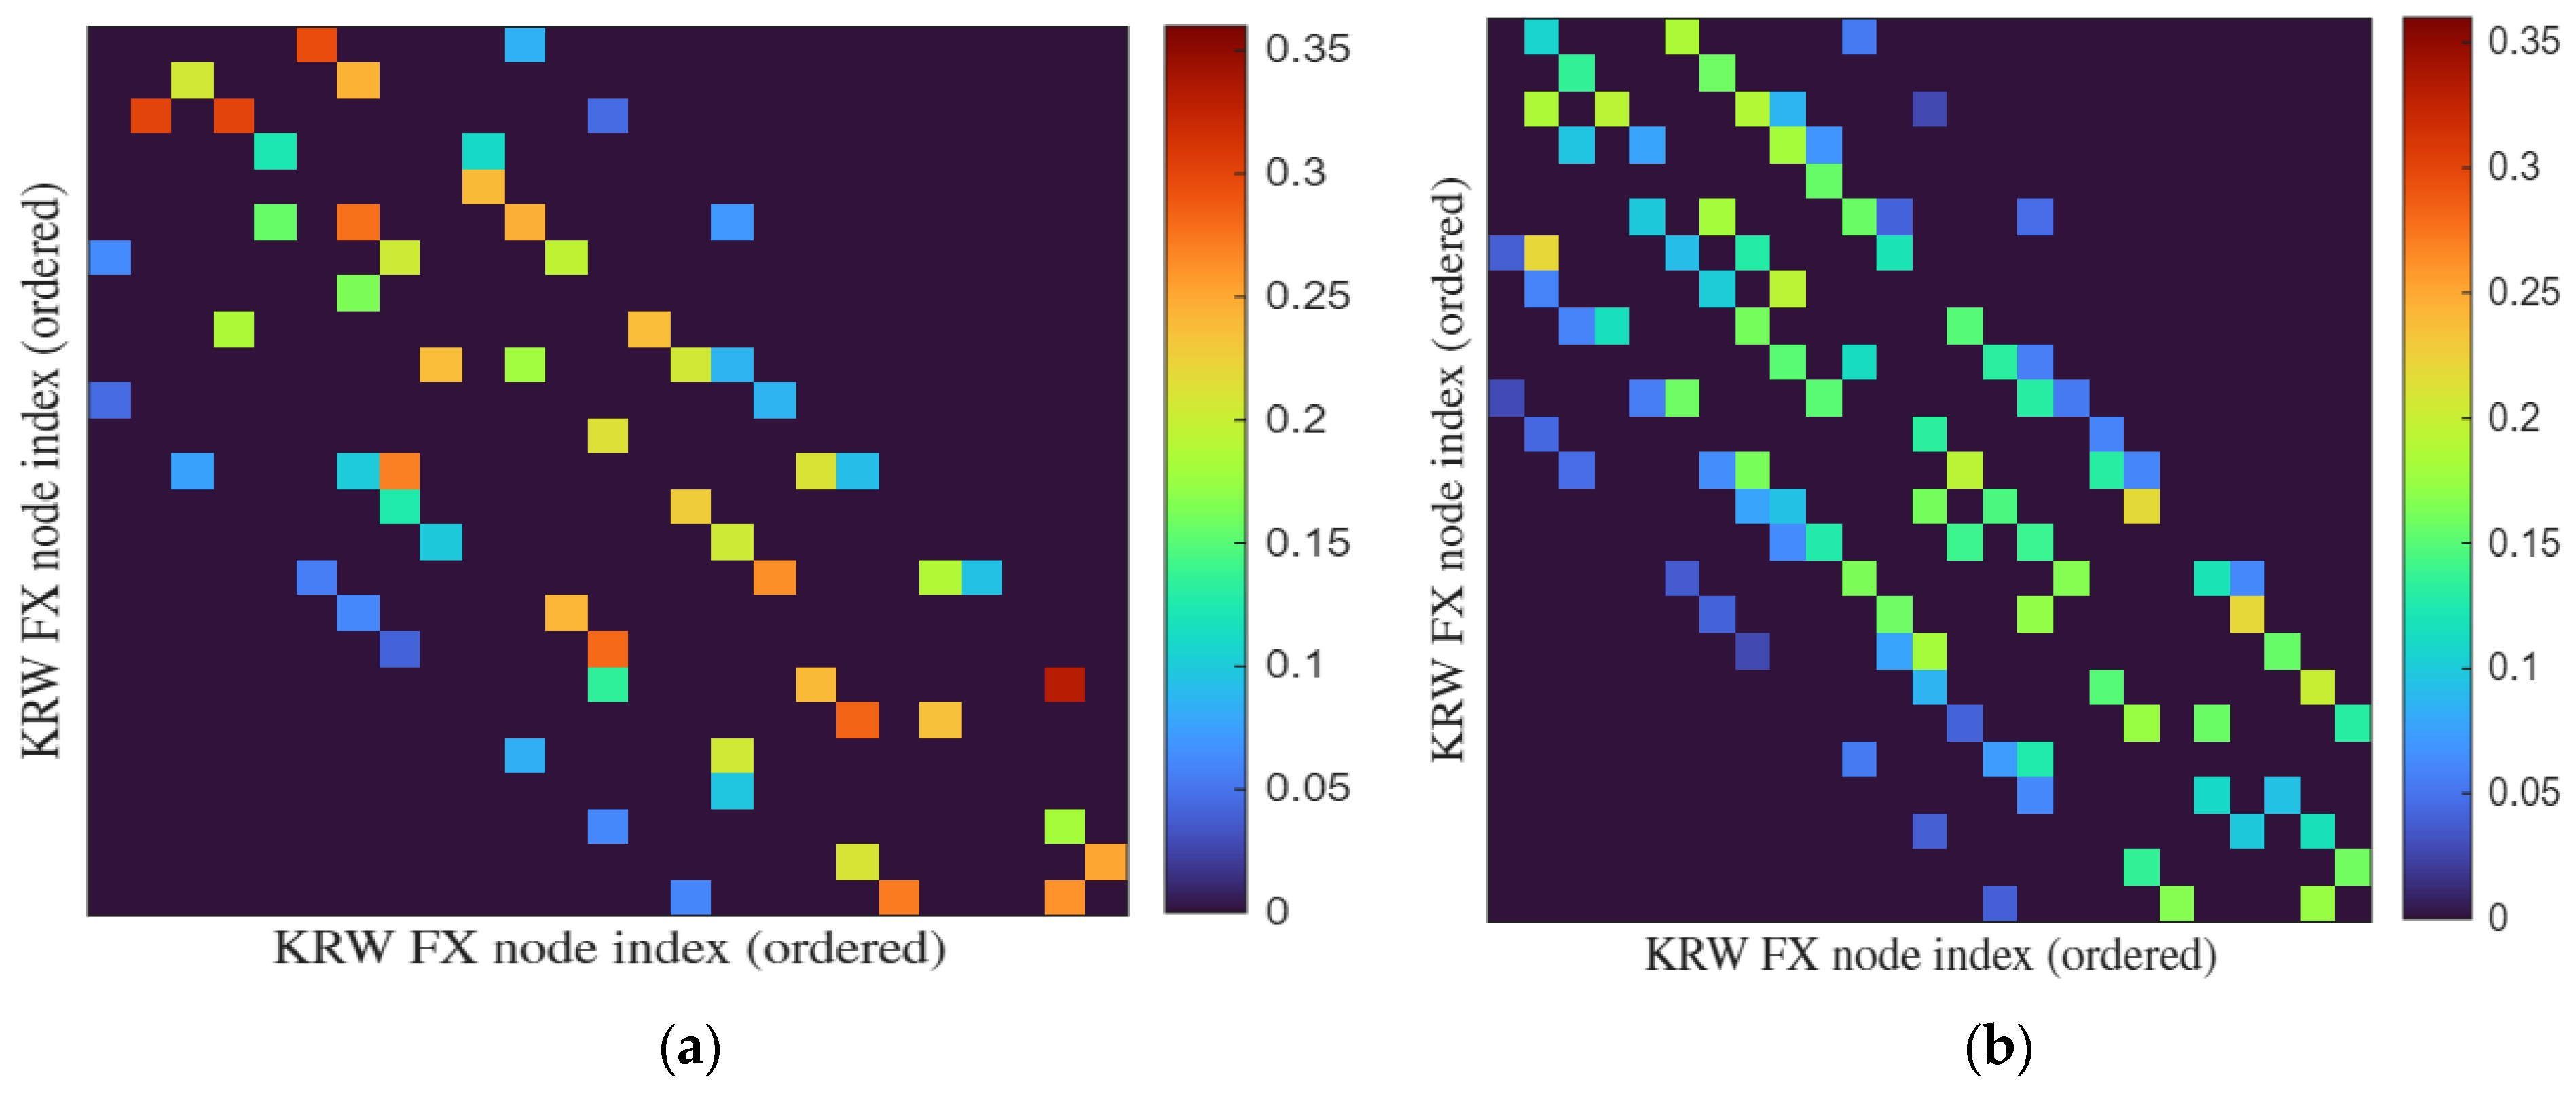
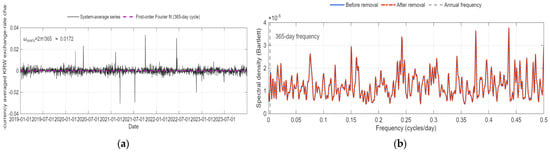
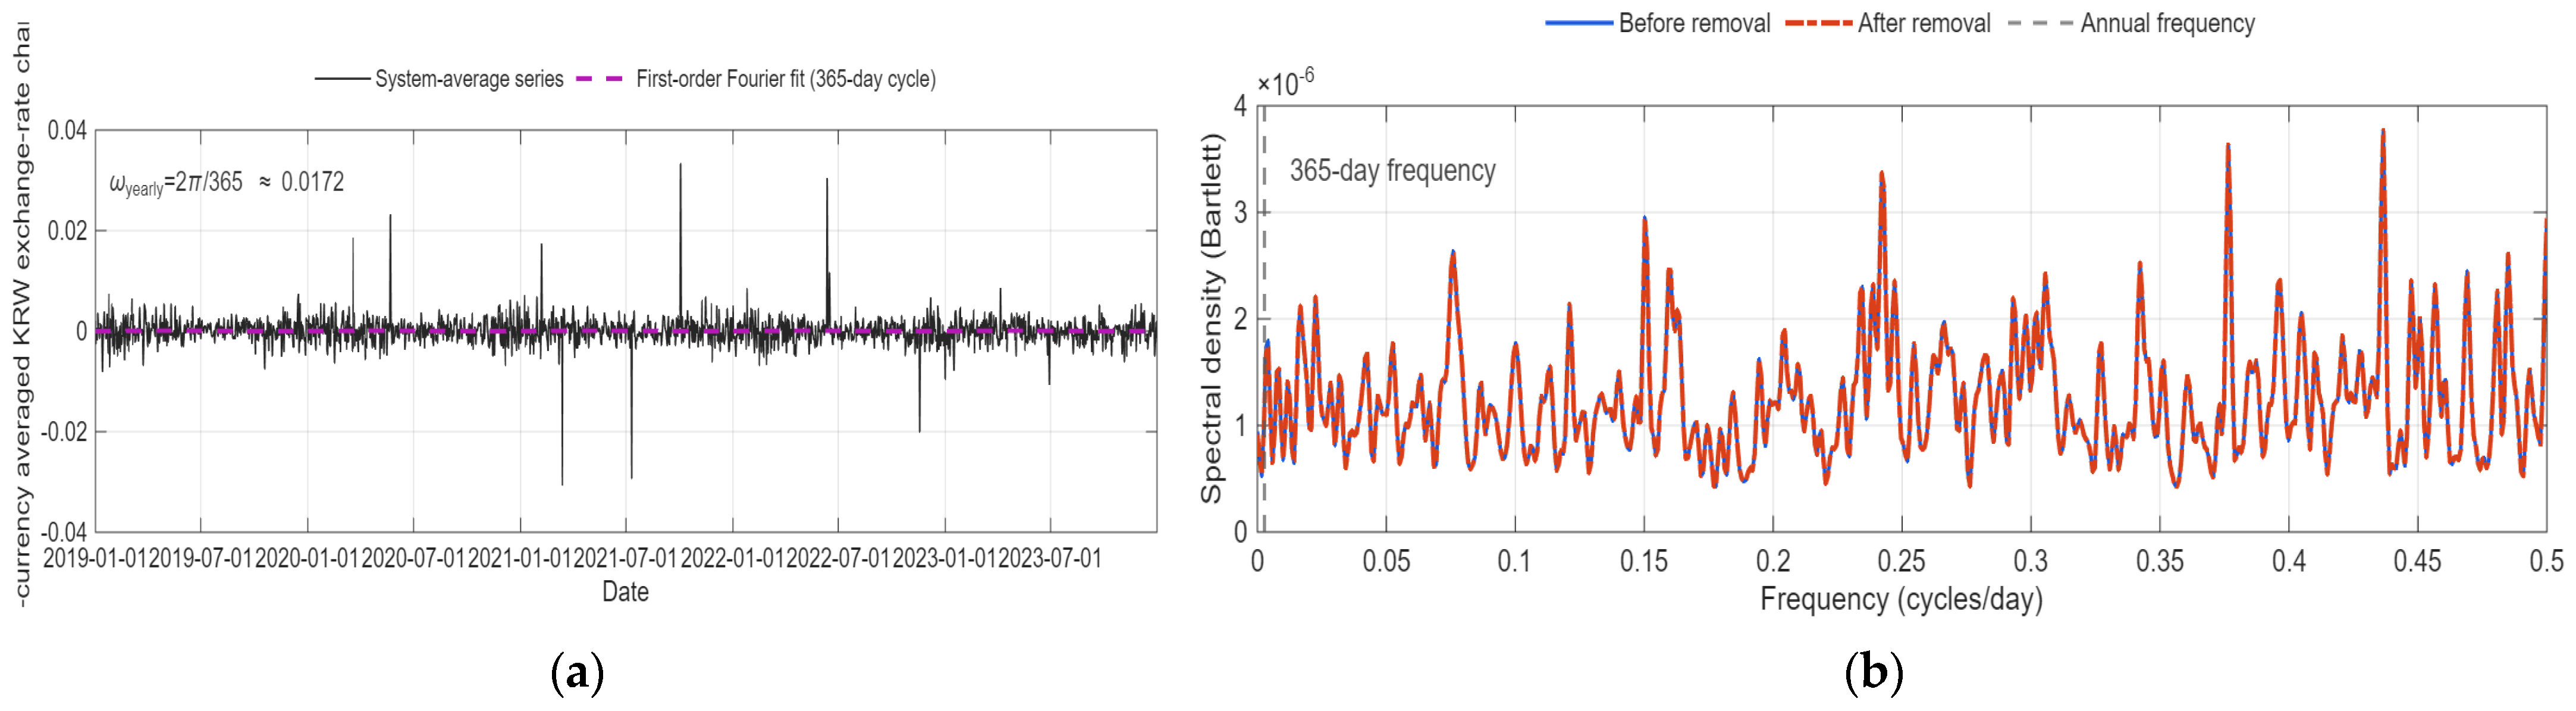
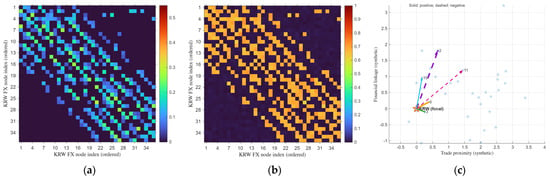
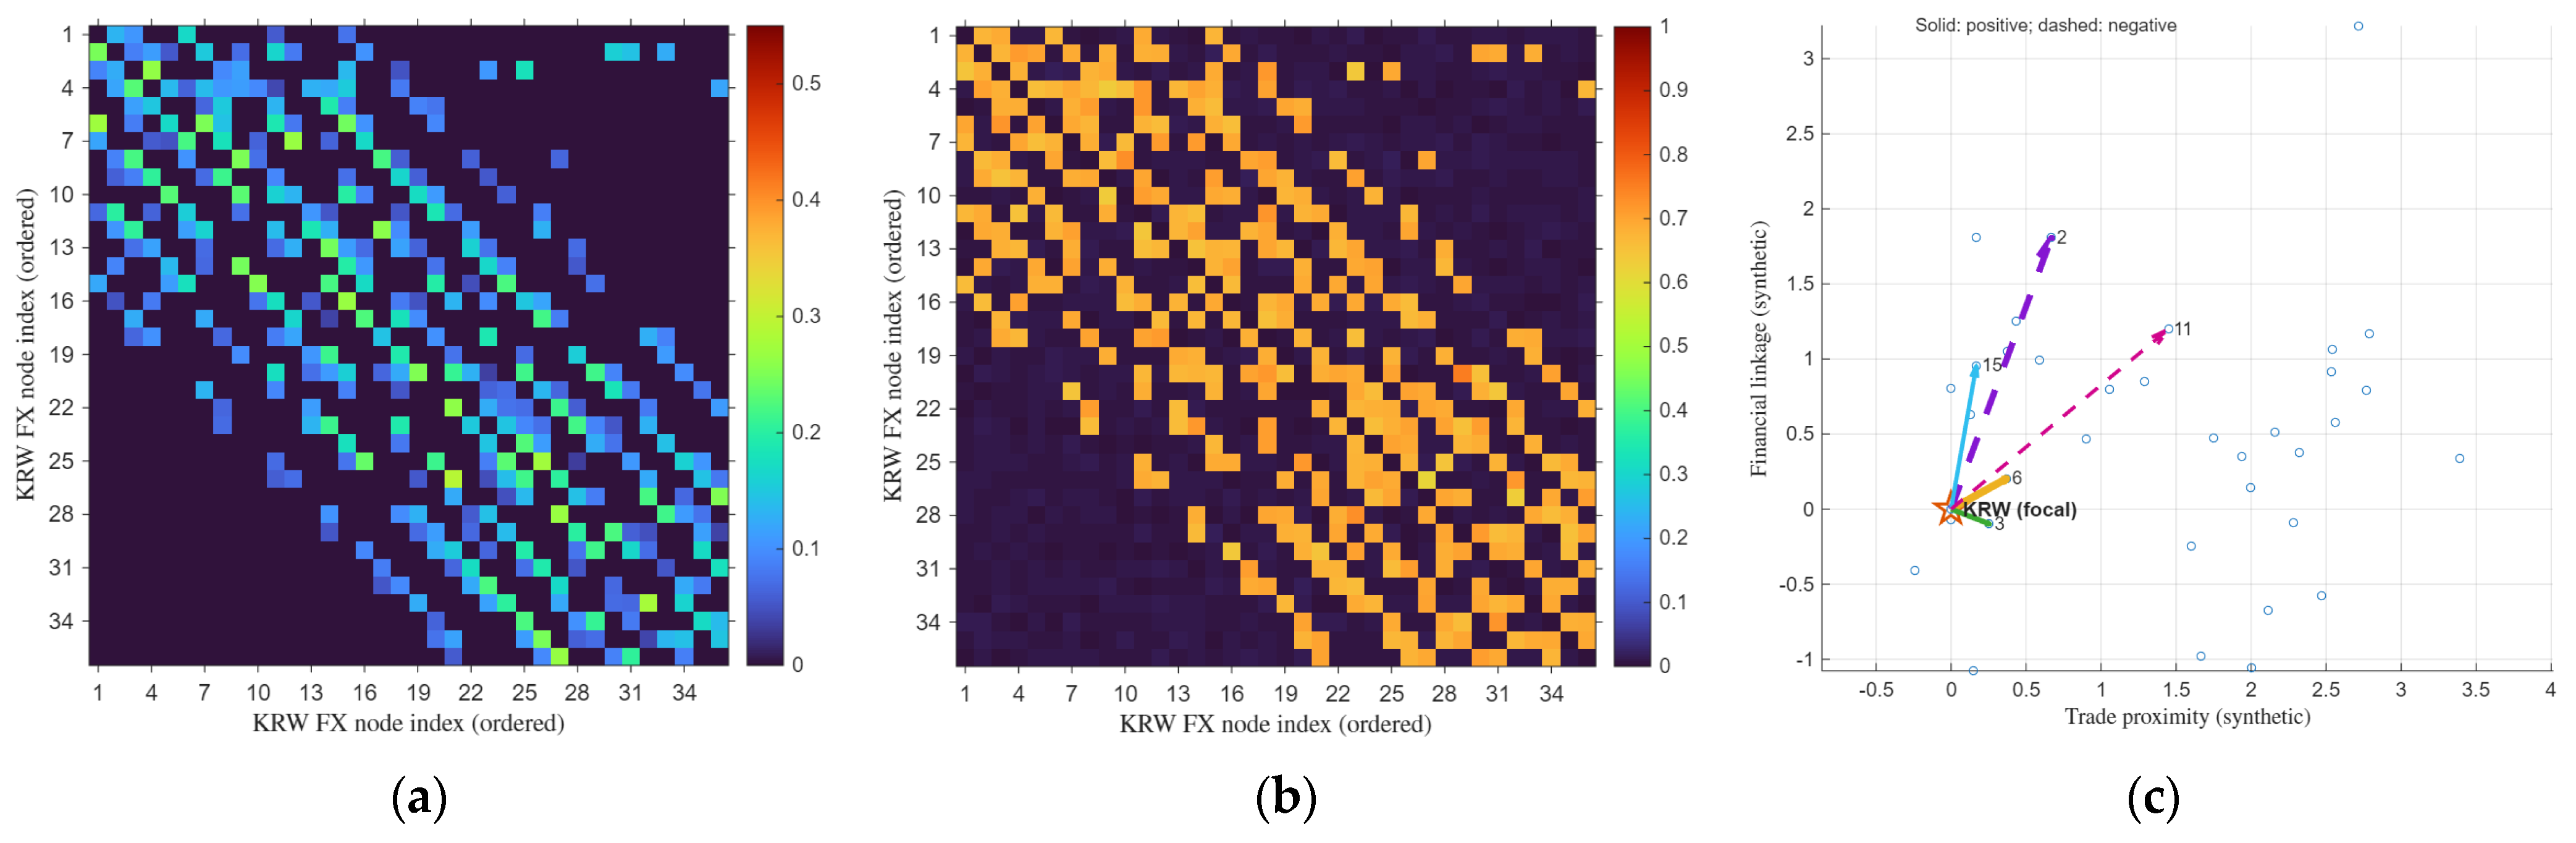

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.