3.1. Semiparametric NAR (SNAR) Model with Time-Varying Covariates
Similar to the definition of the NAR model, let
be the response variable from the
ith subject at time point
t,
,
. A
q-dimensional covariate variable
for each node
i is assumed to be observable at time
t. Given the adjacency matrix
A, the lag-1 SNAR model can be expressed as
where
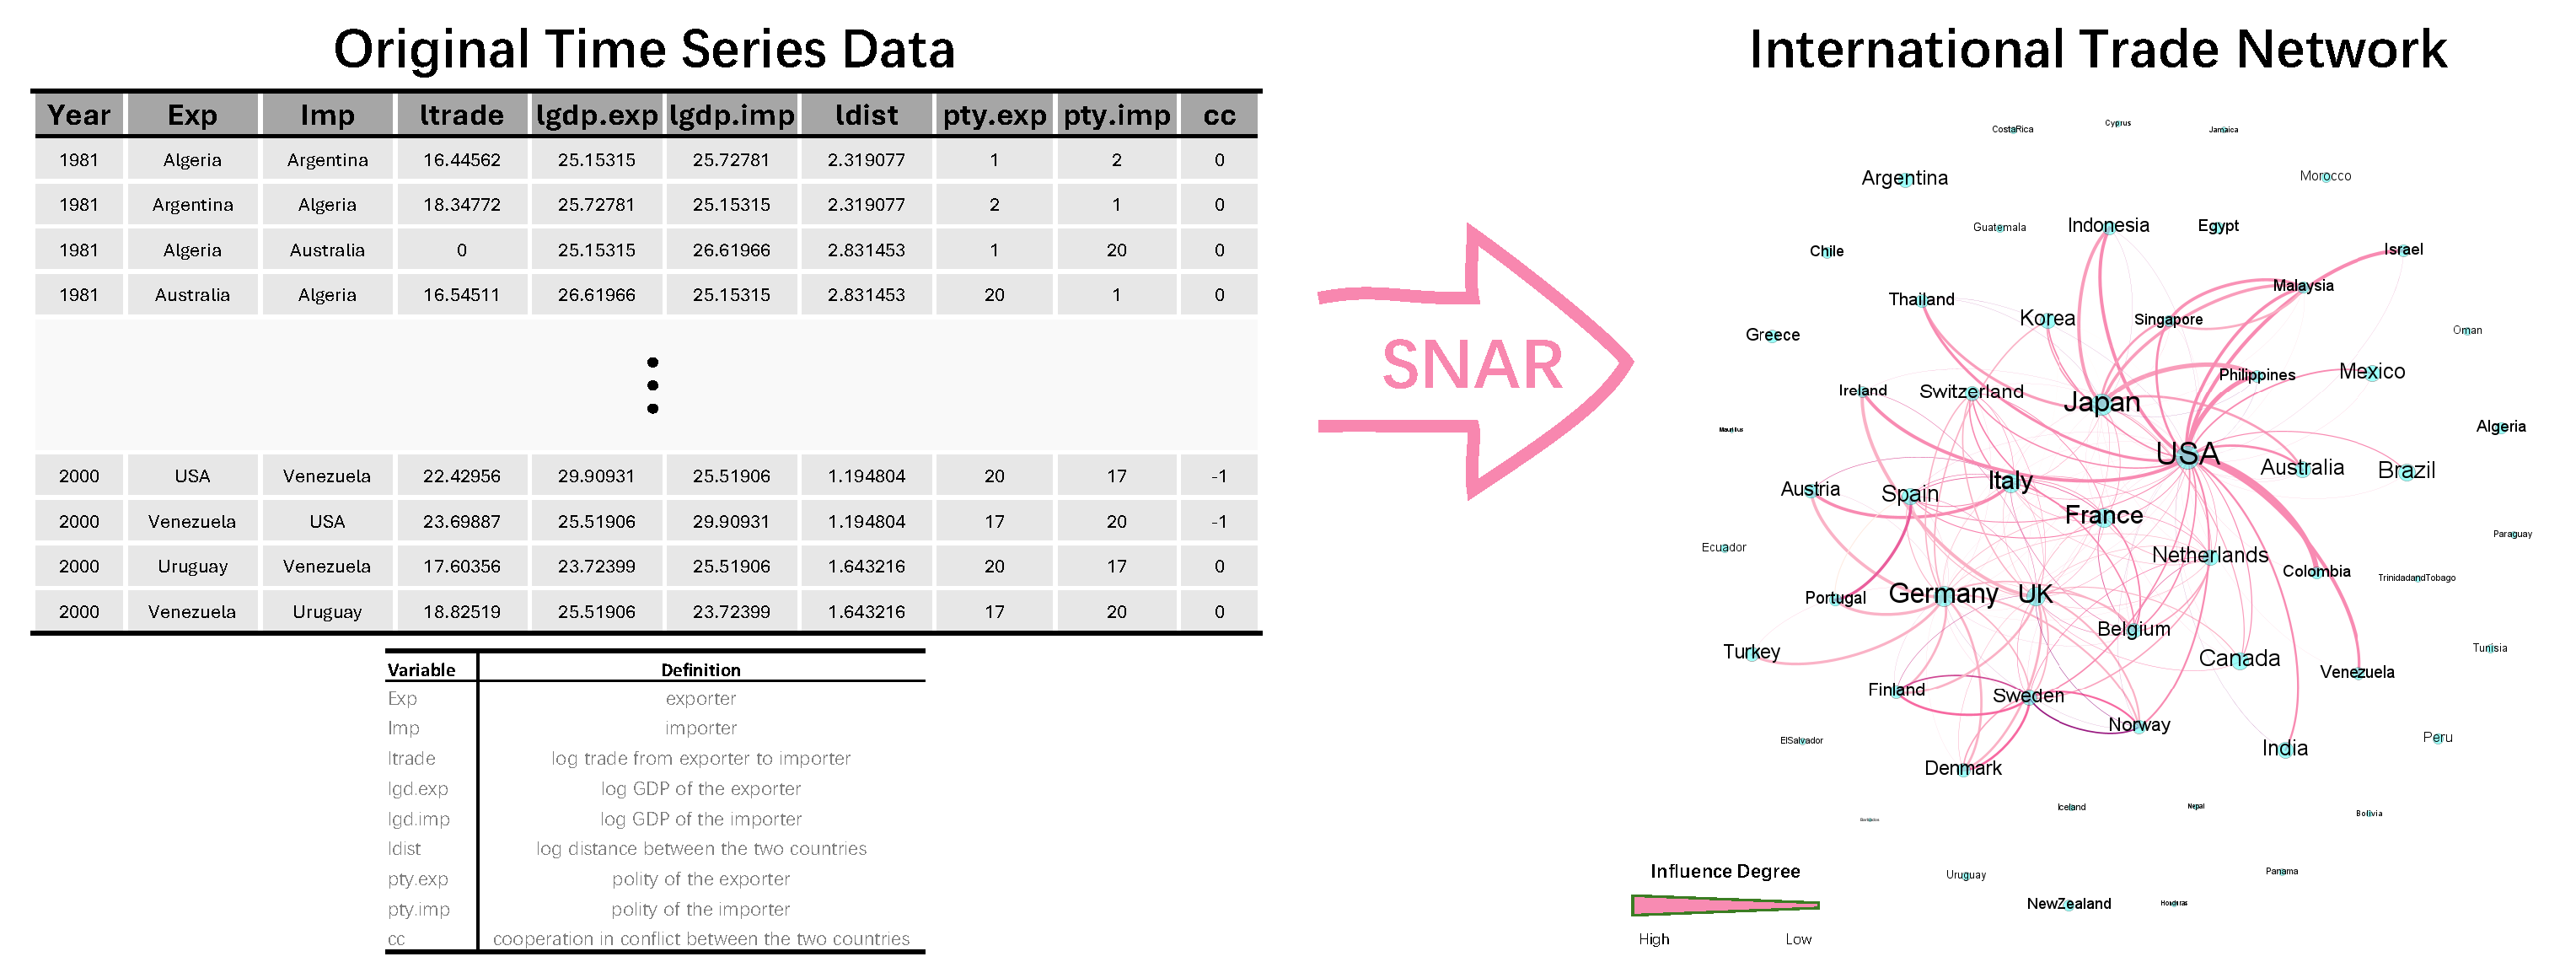
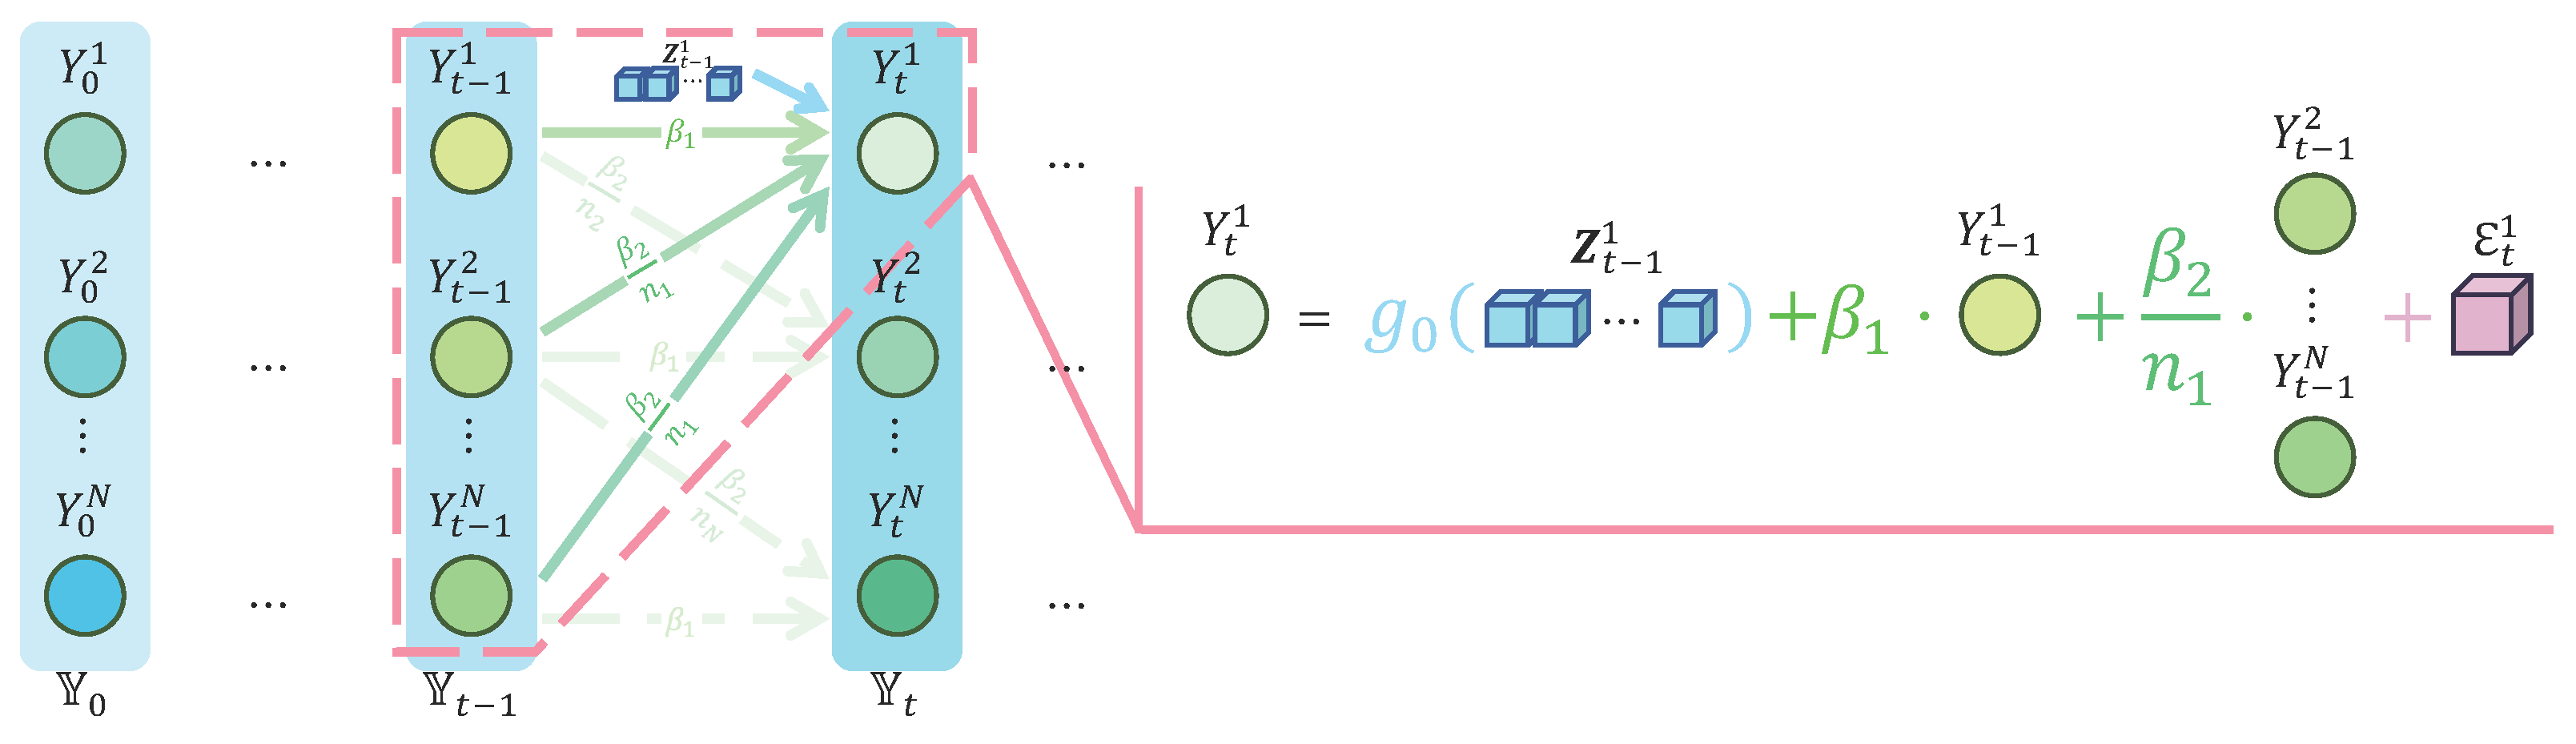
is an unknown function. The architecture of the model is shown in
Figure 2. Its vector form can be written as
where
,
,
,
is the row-normalized adjacency matrix,
I is an identity matrix with compatible dimension, and
. It is obvious that a NAR model in Equation (
2) is a special form of the SNAR model in Equation (
3).
Remark 1.
It is noted that the SNAR model in Equation (2) considers only one lag. One could consider a high-order lag model as a flexible extension. The model setup and assumptions employed in this study are directly based on the framework presented in [1]. Remark 2.
In classic semiparametric models, identifiability is typically ensured by imposing a mean-zero constraint, i.e., , to separate the nonparametric function from the intercept term . Our SNAR formulation adopts an alternative but equivalent approach for identifying the model: we omit the separate intercept parameter and allow to be a general function that absorbs the intercept. This formulation avoids confounding between the constant term and the nonparametric component. Theoretically, one can always decompose the estimated function as , where and , ensuring that the components remain interpretable.
3.2. Estimation
To estimate the unknown function
, deep neural networks (DNNs) are used as function approximators ([
9,
10]). A simple DNN is defined as shown in the appendix. To obtain some theoretical properties shown in the next subsection, we define some classes of DNN. Let
be the set of all positive natural numbers. Given
and
, consider a class of DNN:
where
denotes the sup-norm of matrix or vector, the matrix entries
are the weight linking the
jth neuron in layer
k to the
ith neuron in layer
, and the vector entries
represent a shift term associated with the
ith neuron in layer
.
To avoid the overfitting problem, consider, for
and
, a class of sparse neural networks:
where
is the number of nonzero entries of the matrix or vector, and
is the sup-norm of function
g.
We approximate
using a DNN
, whose input is the
q-dimensional vector
and the output is a scalar value. With the shorthand
and denotation
, we estimate
by maximizing the log likelihood as
where
. The Adam optimizer ([
11]) is used to implement the maximization procedure. We summarize the entire estimation process in Algorithm 1. To prevent overfitting during the training of the nonlinear component
, we employ standard regularization techniques within the network architecture, specifically Dropout layers, alongside an Early Stopping mechanism based on validation loss.
| Algorithm 1 SNAR |
- Require:
{, for and }, Objective Function , Number of Layers, Neurons per Layer, Epochs, Batch Size, Early Stop, Threshold for Minimum Improvement, Learning Rate , Dropout (Optional) - Ensure:
{: The set of , and parameters defining the neural network } - 1:
Set Hyperparameters: Number of Layers, Neurons per Layer, Epochs, Batch Size, Early Stop, Threshold for Minimum Improvement, Dropout (Optional) - 2:
Initialize , (0 as usual) and define the DNN g - 3:
Let U be the reduction in loss from two subsequent training iterations. Initialize as 0 - 4:
Let be the threshold for minimum improvement - 5:
Let - 6:
while U < V do - 7:
Forward Pass - 8:
Pass to the deep neural network, output - 9:
Calculate MSE loss: - 10:
Backward Pass - 11:
- 12:
Stopping Criteria Updates - 13:
If k = 0: Else - 14:
- 15:
end while - 16:
return
|
3.3. Theoretical Properties
We then study the asymptotic properties of the estimators in Equation (
7). Some restrictions on the nonparametric function
are needed. Assume that it belongs to a Hölder class of smooth functions, which has been discussed in [
9,
10,
12]. A Hölder class of smooth functions with parameters
,
and domain
is computed as follows:
where
is the largest integer strictly smaller than
,
with
, and
. Let
,
,
and
,
with
,
, where
is the set of all positive real numbers. We further assume that
belongs to a composite smoothness function class:
Functions in this class are characterized by two kinds of dimensions,
and
, where the latter represents the intrinsic dimension of the function. For this function space, we denote
,
with notation
. To obtain the theoretical properties, the following technical conditions are required:
(A1) The nonparametric function is an element of .
(A2) The neural network family
is defined as shown in Equation (
6), where
,
, and
.
Assumption (A1) assumes that the real
is the composite of some univariate Hölder smoothness functions. Assumption (A2) determines the structure of the neural network family in Equation (
6). According to [
10,
12,
13], more flexible neural networks can achieve smaller approximation error. The approximation error is defined as the distance between true functions
and
, and
is projected onto the space of functions that can be implemented by a neural network from
. However, a larger neural network often leads to a larger estimation error, shown as the distance between
and
. Assumption (A2) is used to provide a trade-off between the approximation error and estimation error.
For the social network structure, assume W is a sequence of matrices indexed by N. They are assumed to be nonstochastic.
(B1) (Connectivity) Treat W as a transition probability matrix of a Markov chain, whose state space is defined as the set of all the nodes in the network. The Markov chain is irreducible and aperiodic.
(B2) (Uniformity) Define as a symmetric matrix. Assume the largest absolute eigenvalues of is .
For the covariates and error term in model Equation (
3), there is a standard assumption for the NAR model.
(B3) Assume that forms a stationary -mixing process with a finite fourth-order moment. This weak dependence condition is standard in time series analysis and is required to ensure the validity of concentration inequalities and central limit theorem-type results used in deriving the consistency and asymptotic properties of the proposed estimators. Without loss of generality, we assume that the domain of is taken to be . are assumed to follow i.i.d. normal distribution with zero mean across both and . Moreover, and are assumed to be mutually independent.
Similar to a usual NAR model, we first introduce the strict stationarity of the SNAR model in Theorem 1.
Theorem 1
(Stationarity)
. Suppose that N is fixed and given for all i and t. If , then there exists a unique strictly stationary solution with a finite first-order moment to the model (Equation (3)). The solution has the following form: Proposition 1.
Assume and . The strictly stationary solution in (Equation (10)) follows a normal distribution with the mean and covariance given bywhere ⊗
is the Kronecker product and is the operator stacking the columns of a given matrix. The proof of Theorem 1 is given in
Appendix B.1. Based on the strictly stationary solution Equation (
10), the conditional mean and covariance of
can be obtained in Proposition 1.
Theorem 2.
Assume the stationary condition and technical conditions (A1) (A2) (B1) (B2) (B3) hold; then, there exists an estimator such thatwhere for any function h is the -norm of h. Theorem 2 reveals that the convergence rates are jointly determined by the smoothness
and the intrinsic dimension
of the function
, rather than the dimension
, under the assumption of the representational space
in Equation (
9). Thus, under our DNN-based SNAR model, the curse of dimensionality is alleviated and the convergence rate will be faster when the intrinsic dimension
is relatively low. The minimax lower bound for estimating
is shown below.
Theorem 3.
Assume the stationary condition and technical conditions (A1) (B1) (B2) (B3) hold; then, there exists a constant, , such thatwhere the infimum is taken over all possible estimators based on the observed data. We then show the asymptotic normality of estimated parameters
([
16,
17]). Let
denote the collection of all subfamilies
such that
, and let
Set
as the closed linear span of
. The asymptotic normality and the information bound are shown in Theorem 4.
Theorem 4.
Assume the stationary condition and technical conditions (A1) (A2) (B1) (B2) (B3) hold. If the information matrix is nonsingular and , we havewhere , is the information bound for β. The proof of Theorem 4 is shown in
Appendix B.4, and an estimate of the asymptotic variance
is also provided in
Appendix C.