


Abstract
This work introduces a logic resource-efficient Artificial Neural Network (ANN) controller for embedded control applications on low-density Field-Programmable Gate Array (FPGA) platforms. The proposed design relies on 32-bit fixed-point arithmetic and incorporates an online learning mechanism, enabling the controller to adapt to system variations while maintaining low hardware complexity. Unlike conventional artificial intelligence solutions that require high-performance processors or Graphics Processing Units (GPUs), the proposed approach targets platforms with limited logic, memory, and computational resources. The ANN controller was described using a Hardware Description Language (HDL) and validated via cosimulation between ModelSim and Simulink. A practical comparison was also made between Proportional-Integral-Derivative (PID) control and an ANN for motor position control. The results confirm that the architecture efficiently utilizes FPGA resources, consuming approximately 50% of the available Digital Signal Processor (DSP) units, less than 40% of logic cells, and only 6% of embedded memory blocks. Owing to its modular design, the architecture is inherently scalable, allowing additional inputs or hidden-layer neurons to be incorporated with minimal impact on overall resource usage. Additionally, the computational latency can be precisely determined and scales with clock cycles, enabling precise timing analysis and facilitating integration into real-time embedded control systems.
1. Introduction
ANNs have emerged as a fundamental tool in the field of artificial intelligence, with applications ranging from pattern recognition to controlling complex systems [1]. Inspired by the architecture and functioning of the human brain, ANNs are composed of computational units called artificial neurons, which are organized in layers and interconnected by synaptic weights that are adjusted during a training process [2]. Focusing on control systems, ANNs have been successfully applied to model nonlinear dynamics, implement adaptive and robust control strategies, and approximate control laws that are complex to derive analytically [3]. They are particularly useful in scenarios involving system identification, predictive control, fault detection, and real-time decision-making, especially when dealing with high uncertainty or limited knowledge of the system [4,5,6].
When deploying ANNs in real-time or resource-constrained environments, such as embedded control systems, the choice of numerical representation, particularly between fixed-point and floating-point arithmetic, becomes crucial [7]. Floating-point arithmetic provides a high dynamic range and precision, which is advantageous during training phases and for applications that require accurate numerical representations. However, it imposes a higher computational and memory cost, making it less suitable for low-power microcontrollers or real-time hardware. Conversely, fixed-point arithmetic is more efficient in terms of speed, memory usage, and energy consumption, making it ideal for embedded implementations [8]. However, it suffers from limited dynamic range and precision errors due to quantization. In neural networks, converting floating-point weights and activations to fixed-point format (quantization) can lead to performance degradation if not carefully managed. Recent developments in quantization-aware training and hardware-aware model optimization techniques have enabled fixed-point implementations to closely match the performance of floating-point deployments, allowing for the real-time execution of neural controllers on platforms such as FPGA, DSP, or low-power microcontrollers [9]. Therefore, the trade-off between precision and computational efficiency must be carefully balanced during the design phase to ensure both reliable inference and efficient resource utilization in practical control systems.
In recent years, FPGAs have emerged as a powerful alternative for neural network inference, especially when real-time performance and energy efficiency are critical. Unlike CPUs (which follow a sequential execution) or GPUs (which rely on SIMD-style parallelism), FPGAs allow for custom hardware pipelines, enabling parallel execution of operations at the hardware level [10]. This structure maximizes throughput while minimizing latency by mapping neural network layers directly onto the logic blocks of the FPGA. Furthermore, the use of fixed-point arithmetic combined with dedicated Multiply–Accumulate (MAC) units optimizes both memory and power consumption, since most neural operations (dot products, convolutions) can be expressed as a series of multiply–accumulate steps [11]. Through pipeline design, each stage of the neural computation (multiplication, accumulation, activation) can be overlapped, ensuring continuous data flow and making FPGAs exceptionally efficient for inference tasks. Consequently, FPGAs strike an optimal balance between resource utilization, power efficiency, and deterministic performance, making them well-suited for embedded neural controllers [12].
However, despite their architectural advantages, the effective implementation of neural networks on FPGAs is strongly dependent on the available hardware resources. While high-density FPGAs can accommodate parallel execution units, deep pipelines, and on-chip memory buffers required for complex models, low-cost or resource-constrained FPGAs may not offer sufficient logic cells, DSP blocks, or Random Access Memory (RAM) to support deep or wide neural architectures [13]. In such cases, developers must adopt strategies like network compression, weight quantization, pruning, or time-multiplexed execution, where the same MAC units are reused across multiple layers or neurons through sequential scheduling. These techniques enable neural networks to operate on minimal hardware, but they often introduce trade-offs among inference latency, throughput, and accuracy. Consequently, for embedded neural controllers implemented on small-scale FPGAs, a careful co-design of the neural model and the hardware architecture is essential to guarantee a functional deployment without exceeding timing or resource constraints [14].
The main contributions of the proposed work are summarized as follows:
- A methodology is introduced for the design of a feedforward ANN implemented on reconfigurable hardware, using 32-bit fixed-point arithmetic. The main objective is to optimize the utilization of logical resources to ensure efficient implementation.
- It is demonstrated that the proposed design can be implemented on FPGAs with limited logic resources. Furthermore, thanks to its modular architecture, resource consumption shows limited variation for the tested configuration even as the number of neurons in the hidden layer or the number of input variables increases.
- Experimental validation, performed through cosimulations, demonstrates the robustness of the system against linear, nonlinear, and unstable plants, evaluated through settling times in the face of reference changes and the presence of disturbances.
- Practical validation is conducted through the comparison of a PID controller and the ANN for the position control of a motor; the values observed are the overshoot, settling time, and magnitude of the control signal.
The paper is organized as follows: Section 2 presents related work, with an emphasis on the development of neural networks for control applications using reconfigurable hardware. Section 3, Materials and Methods, describes the fundamentals of neural networks and the learning algorithm used, in addition to including the dynamic models of the systems used for design validation. Section 4 presents the experimental results, with special attention to both the dynamic responses of the systems and the use of logical resources in the ANN. Section 5 discusses the results, highlighting the practical implications of the proposed controller, as well as its main advantages and limitations. Finally, Section 6 presents the general conclusions of the work and suggests possible future research directions.
2. Related Works
In recent years, the combined use of ANNs and FPGA devices has gained significant relevance in applications requiring real-time processing, high precision, and low power consumption. This trend has been consolidated thanks to the ability of FPGAs to execute calculations in parallel, optimize the use of logic resources, and adapt to diverse neural architectures, from feedforward and recurrent models to neuromorphic and evolutionary networks [15]. The specialized literature encompasses a diverse range of approaches, varying in complexity, training strategy, and application domain, spanning from industrial and energy control to computer vision and autonomous robotics [16,17,18]. This section reviews representative works that explore different combinations of neural topologies, training methods, and logic occupancy levels in FPGAs, highlighting both the advantages and limitations of each proposal in specific application contexts.
For example, the authors in [19] demonstrate a high logic density in their implementations on FPGA devices, characterized by the intensive use of logic elements, lookup tables (LUTs), registers, memory blocks, and dedicated multipliers, achieving in some cases up to 45% logic occupancy and 100% multiplier occupancy. A representative example is the parallel integration of PID controllers and neural networks for controlling a three-degree-of-freedom pneumatic manipulator robot, where training is performed online. This strategy enables the network to continuously adjust the PID gains in real time based on position and velocity errors, thereby compensating for nonlinearities and enhancing tracking accuracy. This solution is particularly useful in industrial environments, where clean, low-cost, and easy-to-maintain actuators are required. In a second approach, the authors in [20] have implemented a stochastic neural network (SANNs) on FPGAs for processing event camera data, which also features high logic density, employing resources such as LUTs, registers, and memory blocks, along with preprocessing logic in SystemVerilog. Training is performed offline using the MNIST dataset before the inference stage, which runs in real time without weight tuning. Potential applications include computer vision, situational awareness, object detection and tracking, and driver assistance systems, which can leverage the robustness and complexity reduction offered by stochastic computing. The work presented in [21] presents an adaptive control. A proposal has been made for evolutionary neural networks with a hidden layer of 500 neurons and a population of 25 networks per generation, trained online in a closed-loop with the plant. This method eliminates the need for backpropagation and enables optimized control of linear and nonlinear systems, resulting in shorter settling times and reduced overshoots. Its adaptability makes it a robust option in the face of variations in parameters and operating conditions. In another context, the authors in [22] implemented recurrent neural networks (RNNs) for inverter control using 32-bit fixed- and floating-point architectures, making extensive use of logic and memory resources to ensure real-time processing with low latency. Training is conducted offline, where the RNN is trained using system data before deployment. Their goal is to optimize the stability and performance of inverters in renewable energy systems and industrial applications where accuracy and response speed are critical. In the field of neuromorphic computing, the authors in [23] propose spike-driven neural networks (SNNs) implemented on FPGAs, offering massively parallel architectures that are optimized for precise timing and efficient resource utilization. Their training is performed offline, and the FPGA is used exclusively for real-time inference. These solutions are applied in pattern recognition, computer vision, autonomous robotics, and low-power embedded systems, distinguishing themselves for their efficiency and asynchronous operation capabilities. On the other hand, recent studies have explored quantization-aware training techniques to mitigate the performance degradation introduced by low-precision arithmetic in neural networks implemented on hardware platforms [24]. These approaches aim to preserve inference accuracy by explicitly modeling quantization effects during training, often at the cost of increased training complexity and hardware overhead [25]. In parallel, other works have investigated alternative neural architectures and their hardware realization on FPGA platforms. For example, the dynamic analysis and FPGA implementation of multiscroll Hopfield neural networks with memristive elements have been reported, focusing on synchronization behavior and complex neural dynamics rather than control applications or resource-efficient architectures [26]. Additionally, reconfigurable hardware strategies have been proposed to reduce area and logic utilization in FPGA-based neural networks.
While these studies demonstrate the feasibility of implementing neural models on FPGA devices, their objectives differ from the present work, which prioritizes logic resource efficiency and embedded control performance for nonlinear and unstable systems.
3. Materials and Methods
3.1. ANN as a Controller
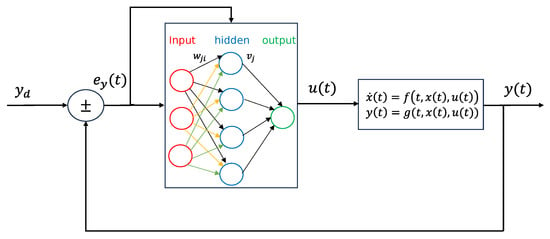
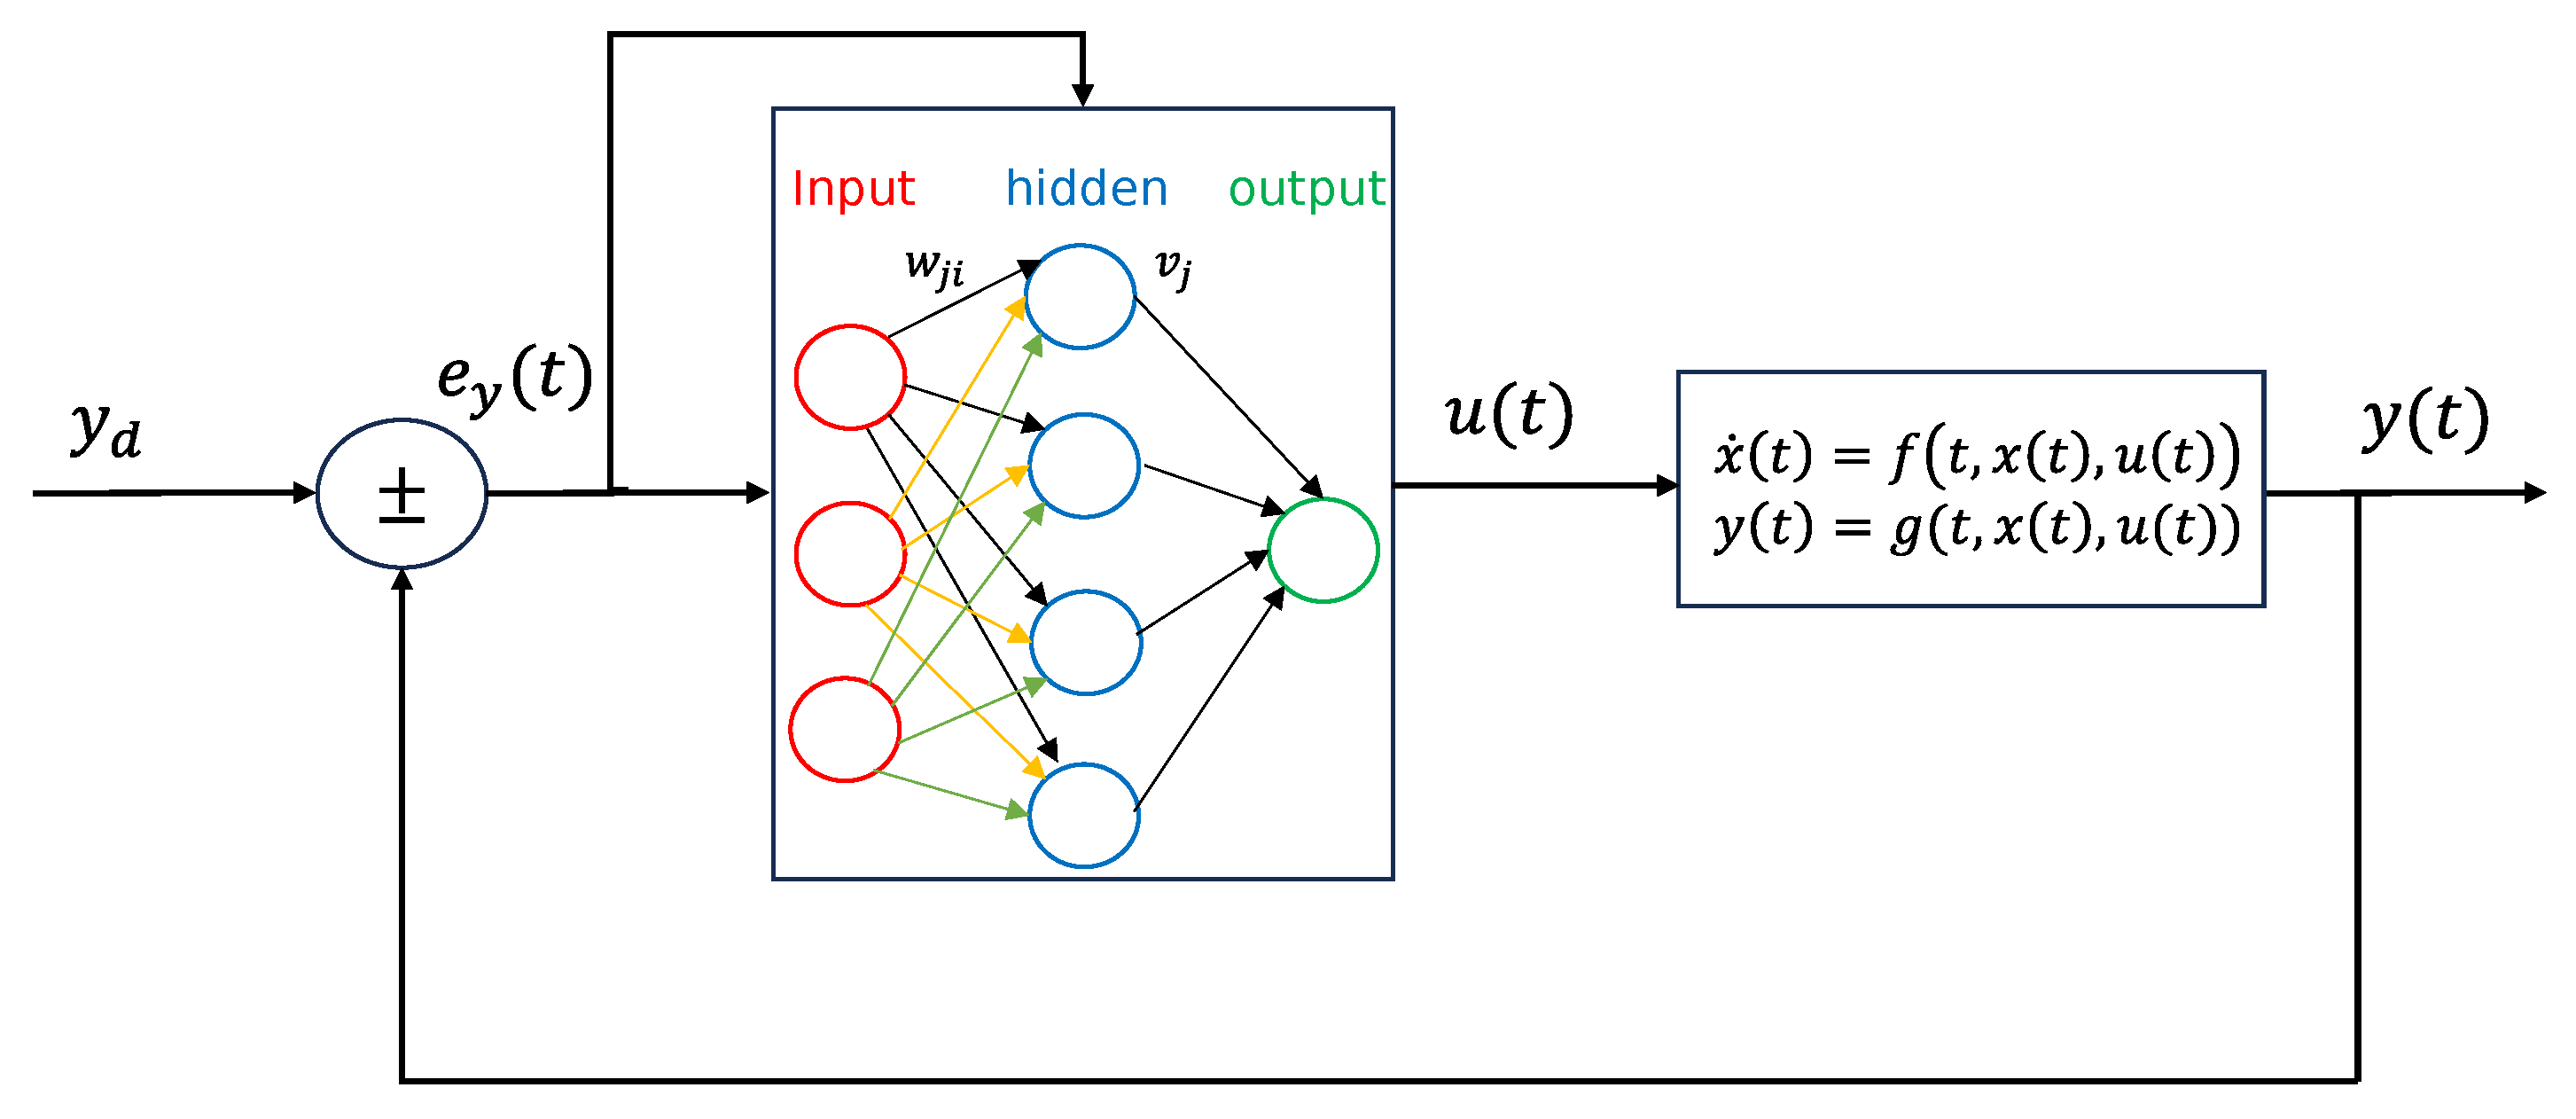
Figure 1 presents the control scheme based on a self-tuning neural network used as a regulator. The architecture used corresponds to a multilayer perceptron with a single hidden layer, which incorporates a dynamic and permanent learning algorithm. The error backpropagation method is used to update the weight coefficients. Unlike conventional schemes, in which the network output is used directly as a control signal, this proposal considers the process error as the primary variable for adjusting the synaptic weights. The network is composed of an input layer with n variables, defined from the current error and its delays, a hidden layer with m neurons, and finally an output layer with a single neuron that generates the control signal.
Figure 1.
Control scheme with self-tuning neural network.
Equation (1) defines the output error of the dynamic system, used as a reference variable for the optimization of the control scheme.
Equation (2) expresses the magnitude of the error generated by the artificial neural network when comparing the estimated output with the desired output. This value is used as a feedback signal for the iterative update of the internal parameters, ensuring the controller’s self-tuning capability.
Within the framework of the scheme shown in Figure 1, Equation (3) describes the input layer of the neural network, constructed from the output error of the dynamical system and its lagged values. This design can be adapted by incorporating additional system variables, which improves the network’s ability to characterize complex dynamics.
3.2. Backpropagation Algorithm
Equation (8) is selected as the objective function. The learning procedure based on the Backpropagation algorithm is formalized in Equations (9)–(11), where and represent the synaptic weights associated with the neurons in the hidden layer and the output layer, respectively. The constant , known as the learning coefficient, plays a crucial role in regulating the magnitude of the weight updates. Its main purpose is to reduce the probability that the error-minimization algorithm becomes trapped in a local minimum, thereby favoring convergence to a global optimal solution. To this end, the analysis of the learning algorithm’s convergence is presented in Section 3.3.
In an ANN, training is generally performed by minimizing the network output error. However, in an ANN as shown in Figure 1, the value of Equation (2) is unknown at any given time because the value of is unknown. Therefore, the cost function is proposed in Equation (8), since this value can be calculated from measurements of the system output.
It is worth mentioning that in Equation (15), the calculation of the term is not highly relevant, since the step size can be adjusted using . It must be true that . Therefore, if the sign of is known at each instant, a simple algorithm is obtained for training the neural network using the system’s output error instead of the network’s output error.
3.3. Analysis and Convergence of the ANN
The stability and convergence analysis for the ANN mentioned in Section 3 is presented below.
The discrete-form Lyapunov function is shown in Equation (16):
The change in the Lyapunov function due to the training process is shown below.
The generalized rule for the learning process is shown below in (20):
3.4. Implementation of the ANN in Hardware Description Language
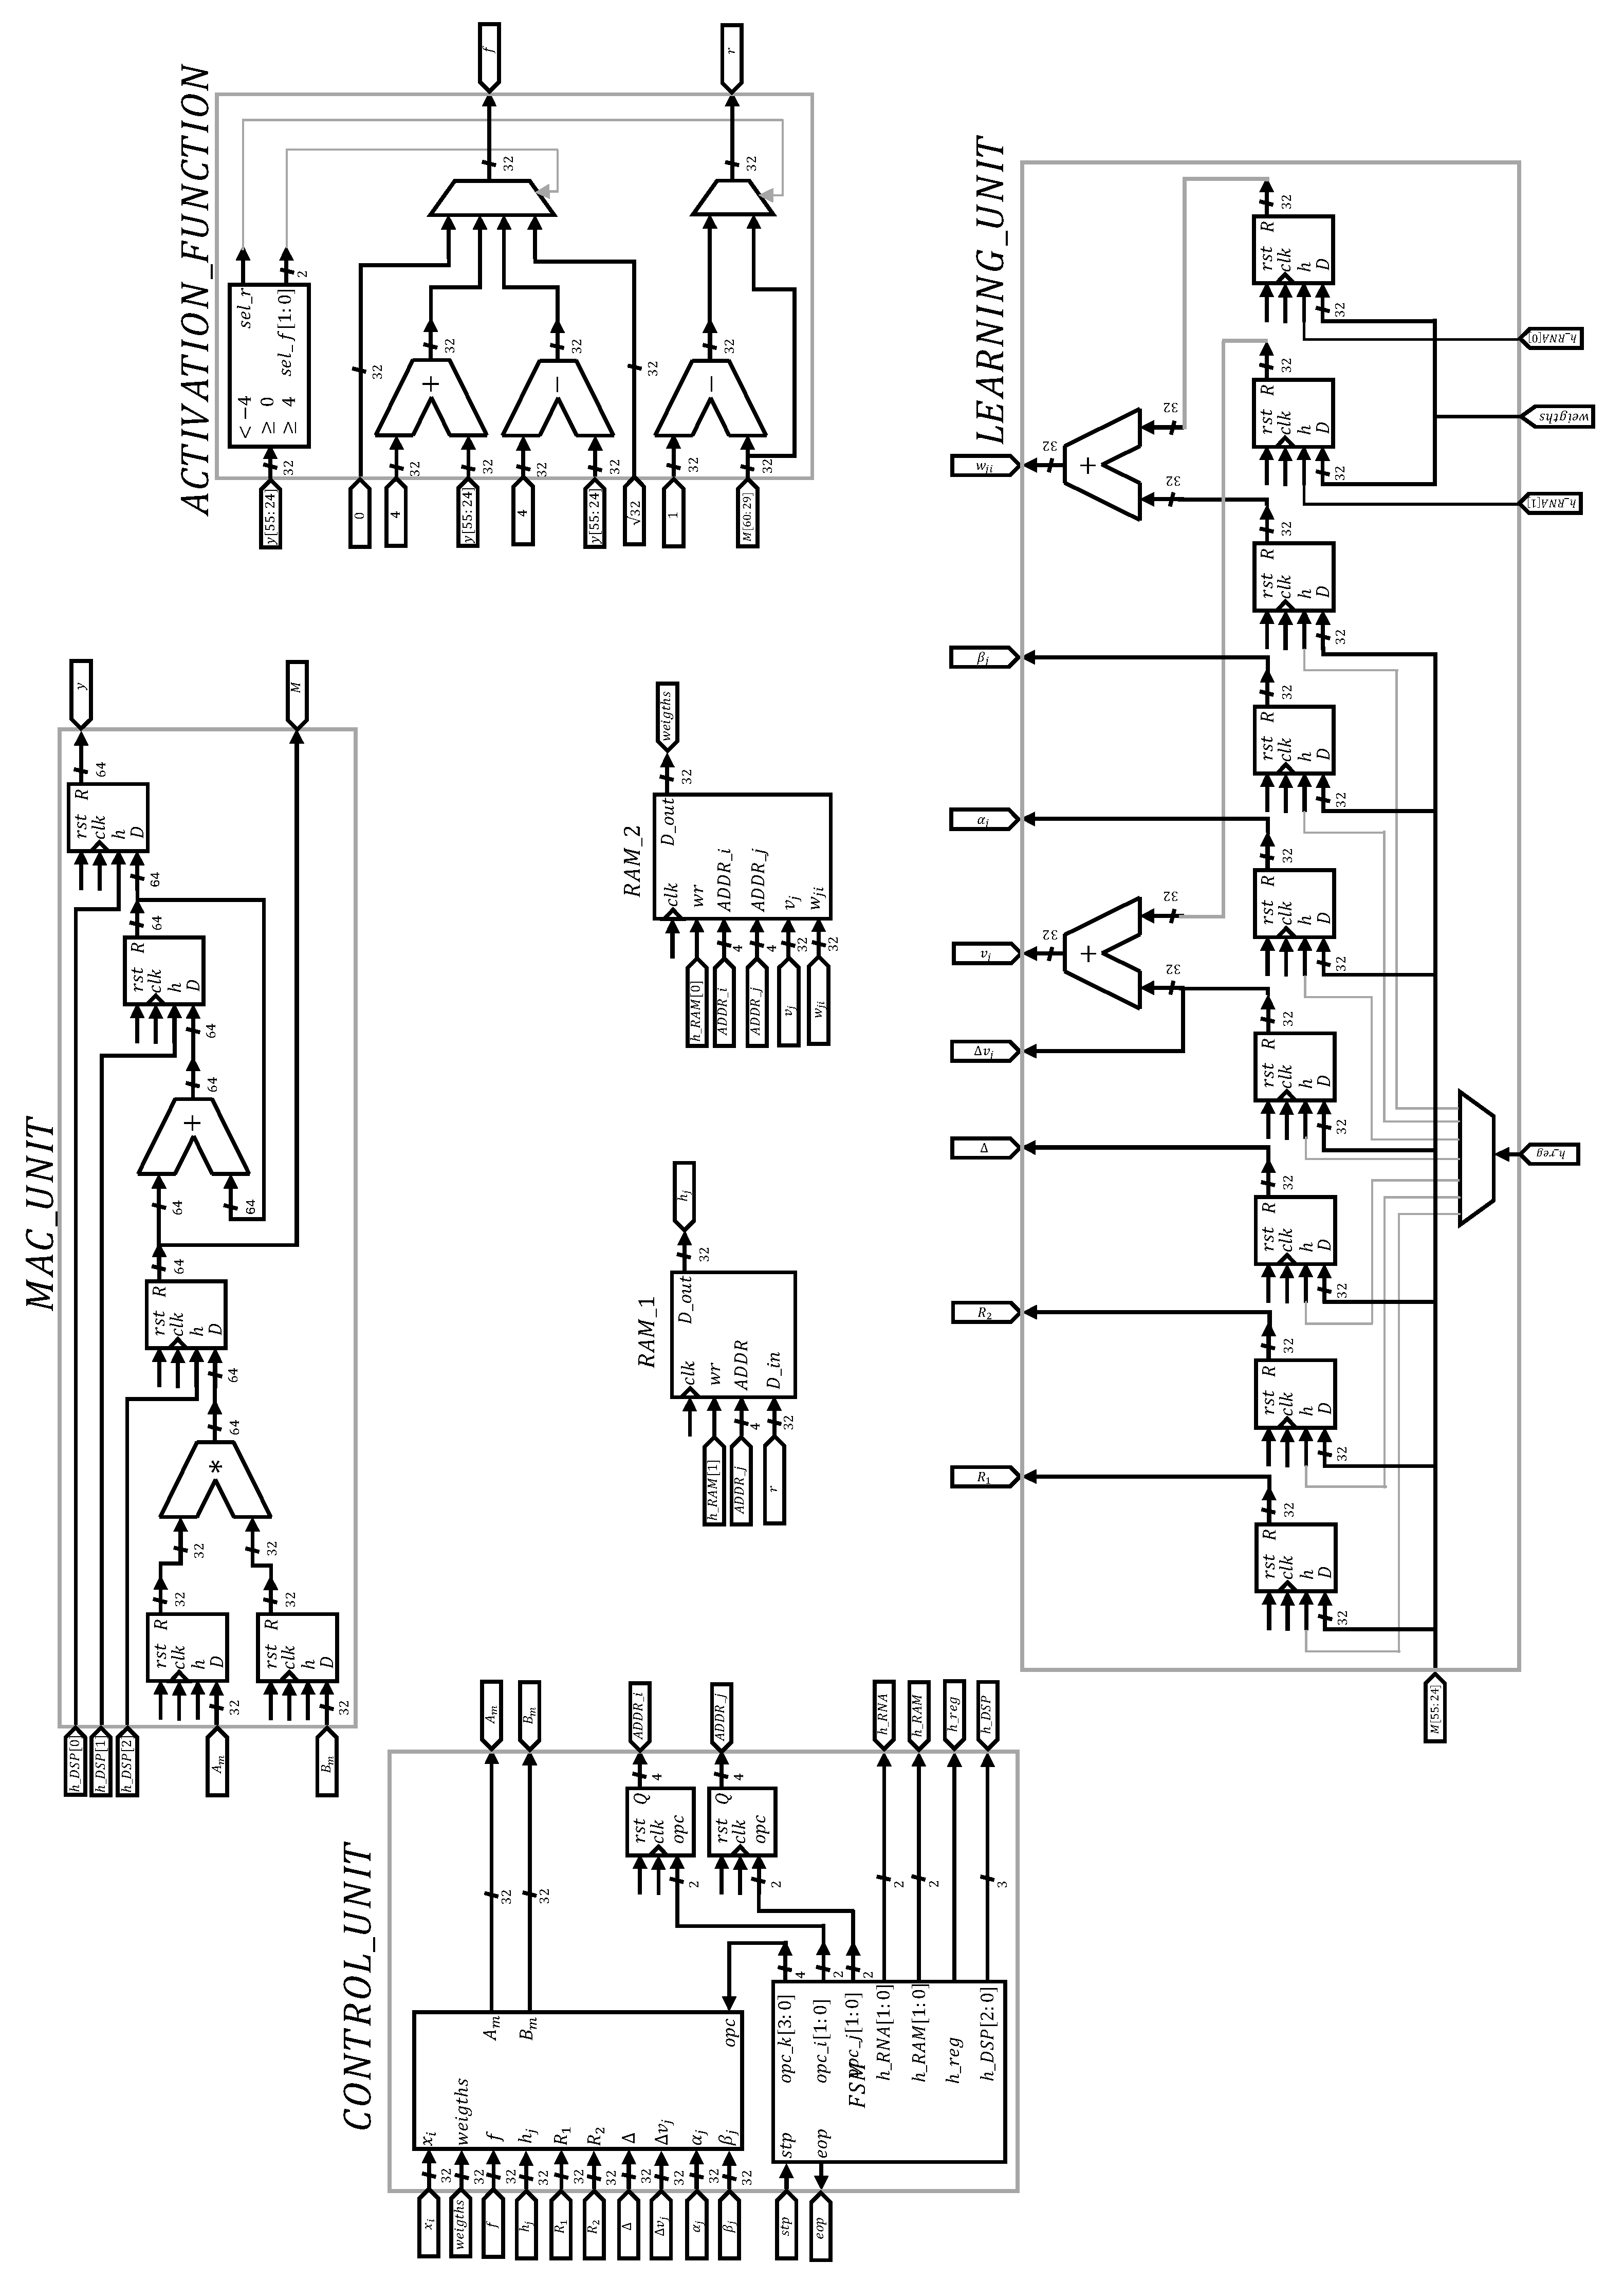
For the hardware description of the self-tuning neural network as a regulator, the primary objective was to optimize the design to utilize the minimum amount of logical resources, enabling its implementation in low-density FPGAs, such as LATTICE ICE40UP5K and XILINX XC3S200A. Initially, a fixed-point representation of the variables, along with fixed-point arithmetic, was adopted, as it does not require specialized modules for arithmetic operations, which can be executed by inferring basic hardware components, such as multipliers and adders. Figure 2 presents the HDL design of the self-tuning ANN as a regulator, consisting of five main blocks: CONTROL_UNIT, in charge of process management and coordination; MAC_UNIT (Multiply–Accumulate Unit), which implements the multiplication and accumulation operations; ACTIVATION_FUNCTION, responsible for applying the selected activation function; LEARNING_UNIT, which performs weight updating via backpropagation; and two RAM memories, used to store parameters and intermediate values. This approach ensures an efficient implementation in terms of logical resources and maintains the flexibility necessary for dynamic controller adaptation. The CONTROL_UNIT module is activated once it receives a stimulus at the input, and its main function is to manage the handling and storage of system variables. Each stored variable has a length of 32 bits, which guarantees adequate precision in control operations. Upon completion of the algorithm execution, this unit sets the signal high, indicating the end of the process. Likewise, the CONTROL_UNIT is responsible for generating the control and address signals for the RAMs, ensuring correct synchronization between the data flow and the processing modules.
Figure 2.
RTL of the ANN as a proposed self-tuning controller.
The MAC_UNIT module is responsible for performing all the operations defined in Equations (4)–(7) and (10)–(15). That is, it constitutes the stage responsible for executing the excitation and activation functions of each neuron in both the hidden layer and the output layer, according to the regulator configuration. Additionally, this module implements the operations required to update the synaptic weights of each neuron using the backpropagation algorithm. The input variables are represented in an 8:24 fixed-point format, with a length of 32 bits. The outputs corresponding to the multiplier and accumulator reach a length of 64 bits, expressed in a 16:48 format. This design infers the use of four multiplier units or DSPs, considering that the proposed FPGAs have internal resources of in the case of LATTICE and in the case of XILINX, respectively.
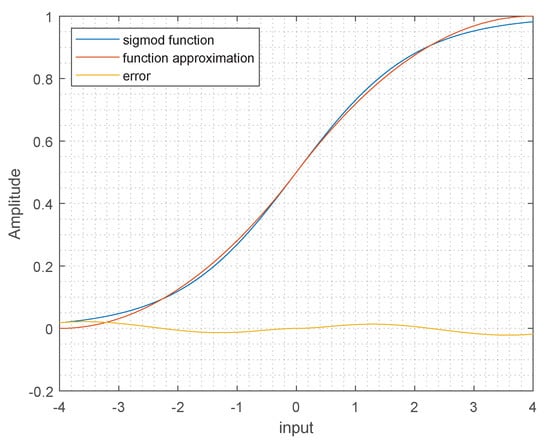
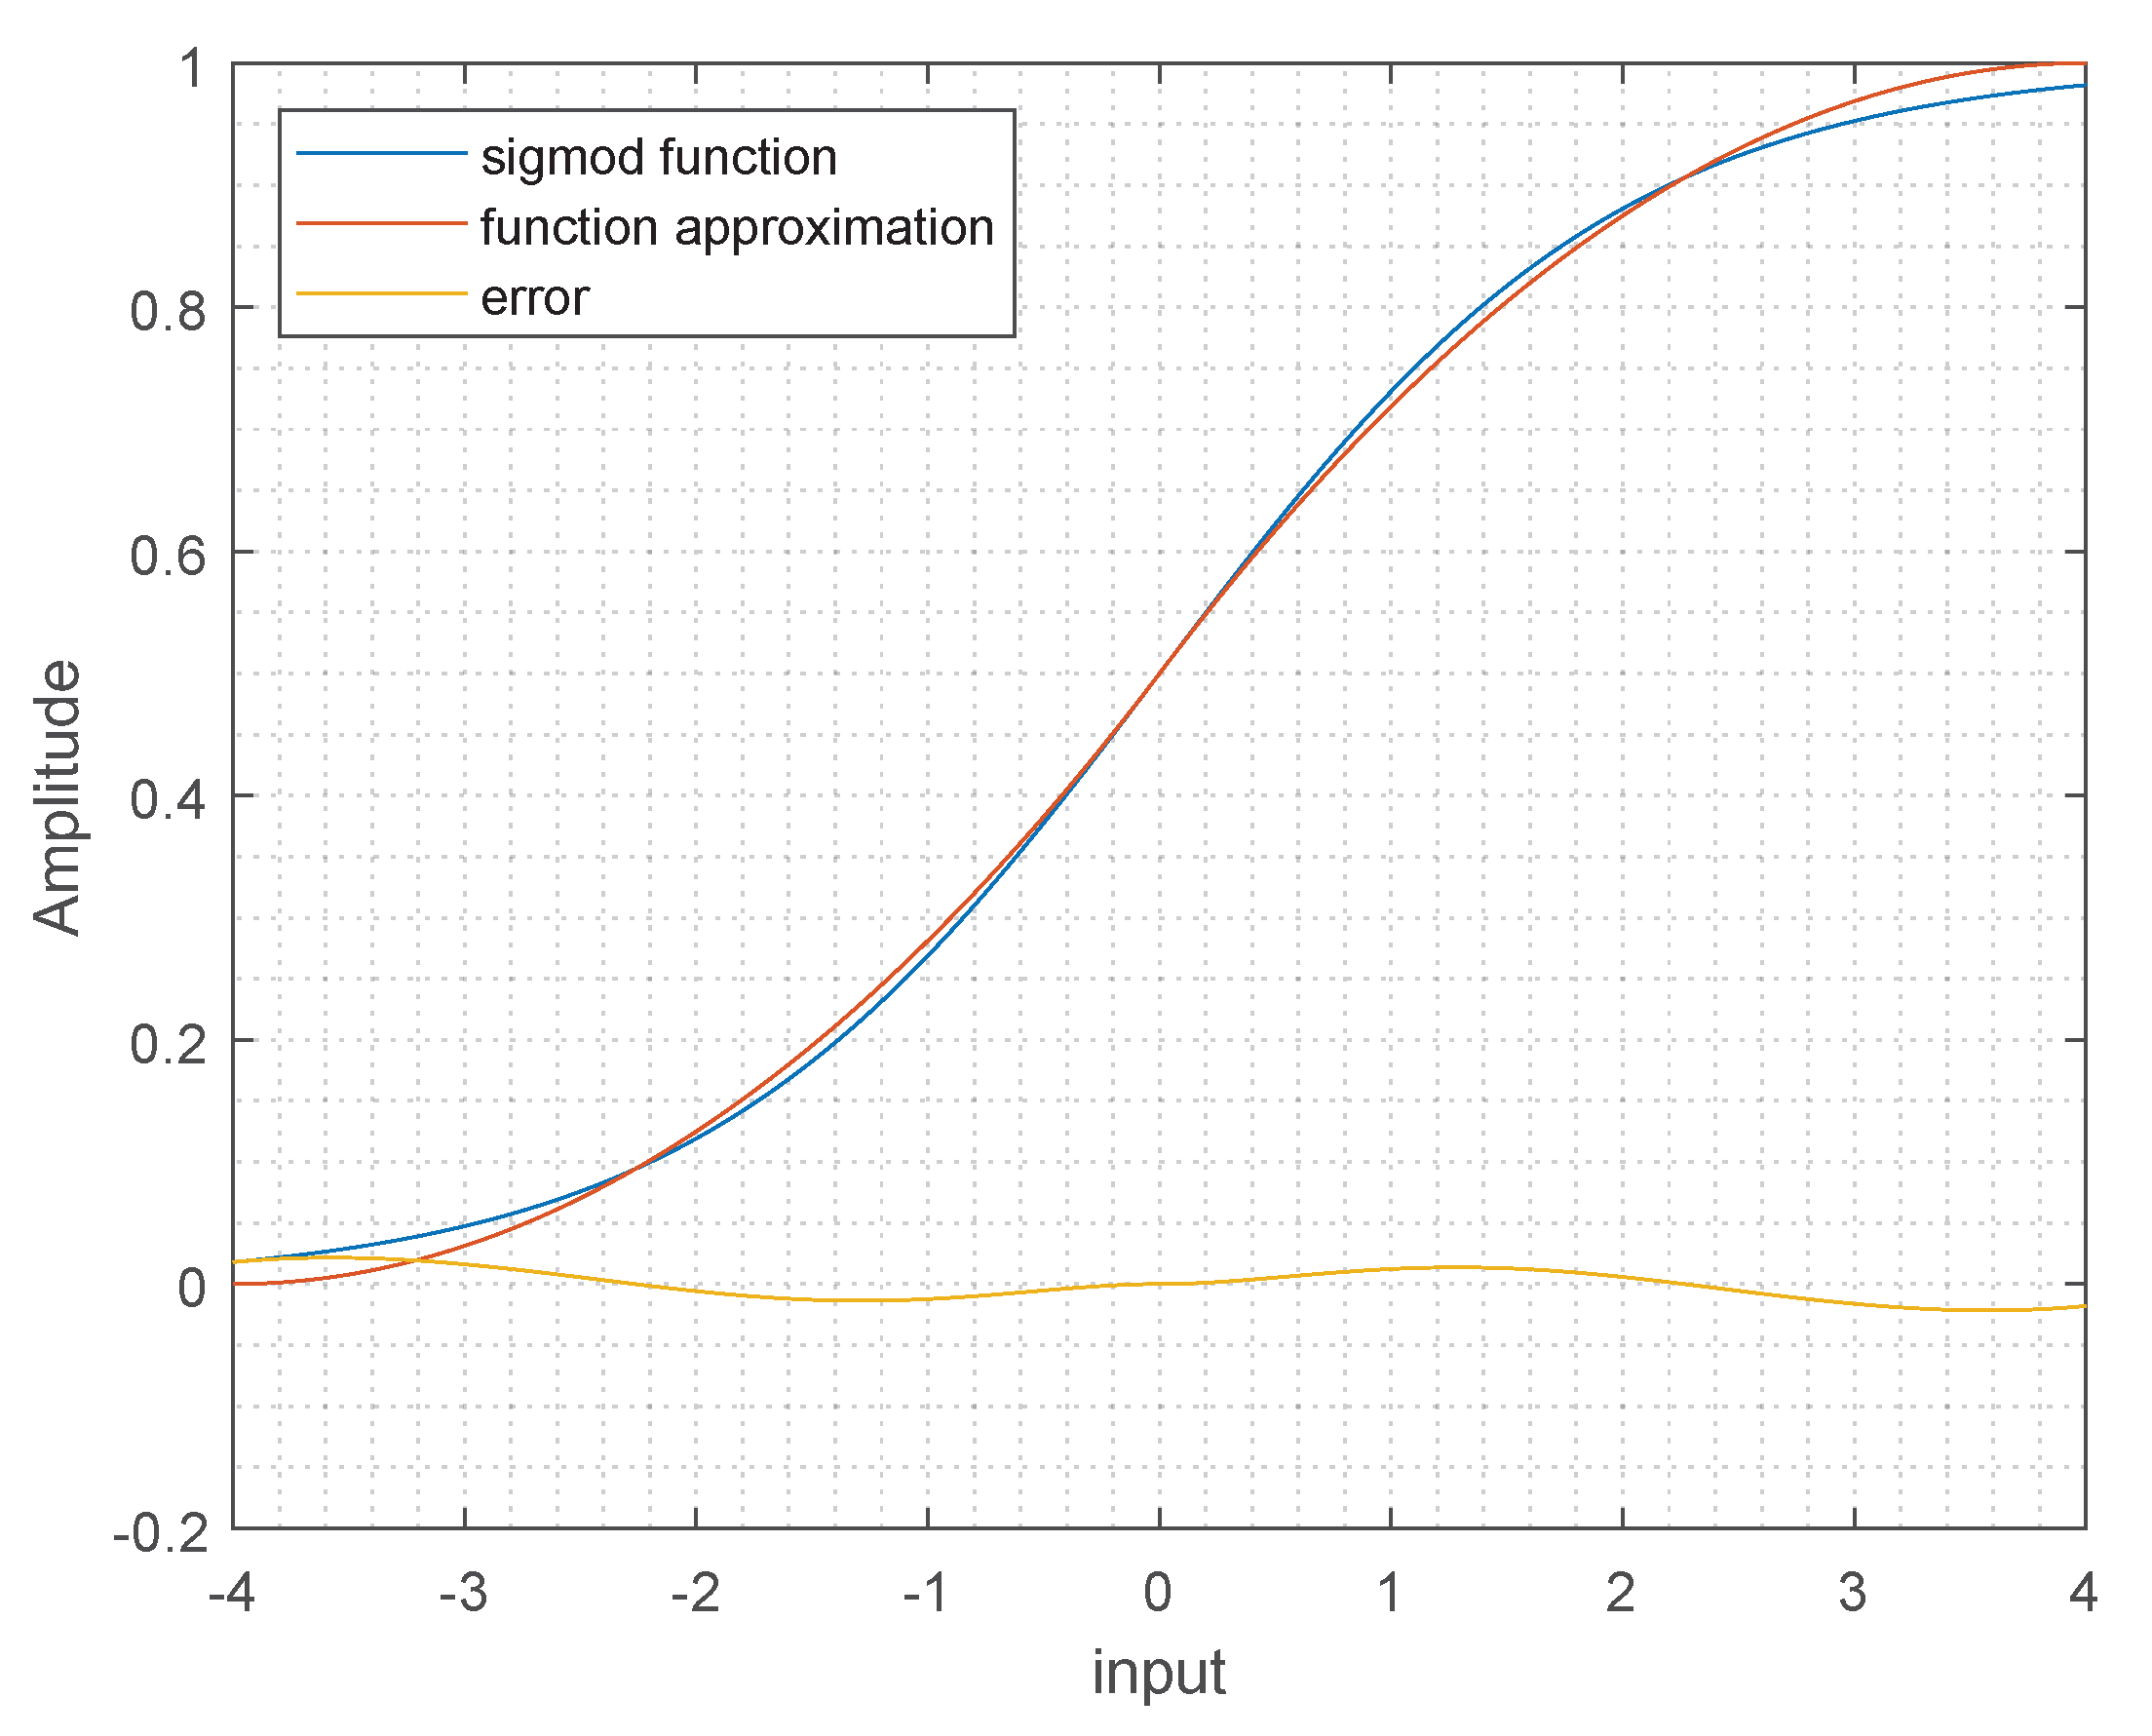
For the ACTIVATION_FUNCTION module, an approximation of the sigmoid function is implemented, which is represented in Equation (23). This approach simplifies the computational complexity of the original function, ensuring lower consumption of logical resources in the FPGA and reducing the computation time, without significantly compromising the performance of the self-tuning neural regulator.
The conventional sigmoid activation function is widely used in artificial neural networks because of its smooth nonlinear behavior and bounded output. Nevertheless, its direct implementation on FPGA platforms is computationally demanding, since it involves exponential and division operations. These operations typically require floating-point units or large lookup tables, resulting in increased logic utilization, DSP usage, and memory consumption. Such requirements conflict with the main objective of this work, which is to achieve an efficient ANN implementation on low-density FPGA devices.
To address this issue, the sigmoid function is approximated using the piecewise-defined function presented in Equation (23). This approximation replaces the exponential computation with simple arithmetic operations, namely additions, multiplications, and comparisons. These operations are well suited for fixed-point arithmetic and can be efficiently mapped onto FPGA architectures. As a result, the proposed activation function significantly reduces hardware complexity while avoiding the need for specialized functional units, leading to lower latency and reduced power consumption.
Figure 3 illustrates the comparison between the original sigmoid function, the proposed approximation, and the corresponding approximation error. Within the interval , where the sigmoid exhibits its highest sensitivity and plays a critical role in the learning process, the approximation closely matches the original function. Outside this interval, both functions saturate, and therefore the approximation does not introduce relevant deviations in the network output.
Figure 3.
Comparison of the sigmoid function and its approximation.
The error profile shown in Figure 3 confirms that the approximation error remains bounded and relatively small within the active region. From a control systems standpoint, this error is negligible when compared to other sources of uncertainty such as modeling inaccuracies, sensor noise, and external disturbances commonly encountered in practical applications. Moreover, the online learning capability of the ANN allows the system to compensate for minor approximation errors during operation, preserving stable and accurate performance.
Within the LEARNING_UNIT module, the intermediate variables necessary for updating the synaptic weights are managed and stored, according to the expressions shown in Equations (10) and (11). This module is responsible for implementing the backpropagation algorithm efficiently in hardware, ensuring the correct adaptation of weight coefficients in real-time. Finally, two dedicated RAMs were described: the first is used to store the variable defined in Equation (5). In contrast, the second memory is used to store all the weights associated with each neuron. This organization enables orderly and efficient access to data, optimizing both the inference stage and the learning phase within the self-tuning neural network.
It is essential to note that this implementation does not necessitate modifications if additional inputs are required or the number of neurons in the hidden layer is increased. Furthermore, the number of cycles required to calculate the control signal and update the weights, based on the number of inputs n and neurons m in the hidden layer, is controlled by the expression . To evaluate the performance of the neural controller as a self-tuning regulator, three dynamic system models are considered. The first corresponds to a linear and stable system: a Direct Current (DC) motor. The second is based on a nonlinear and stable system: a Buck-type DC-DC converter. Finally, the neural network is tested on a nonlinear and unstable system: the Inverted Pendulum on a Cart (IPOC).
3.5. Description of the DC Motor Dynamic Model
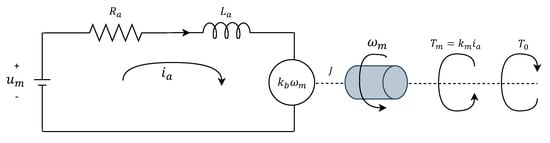
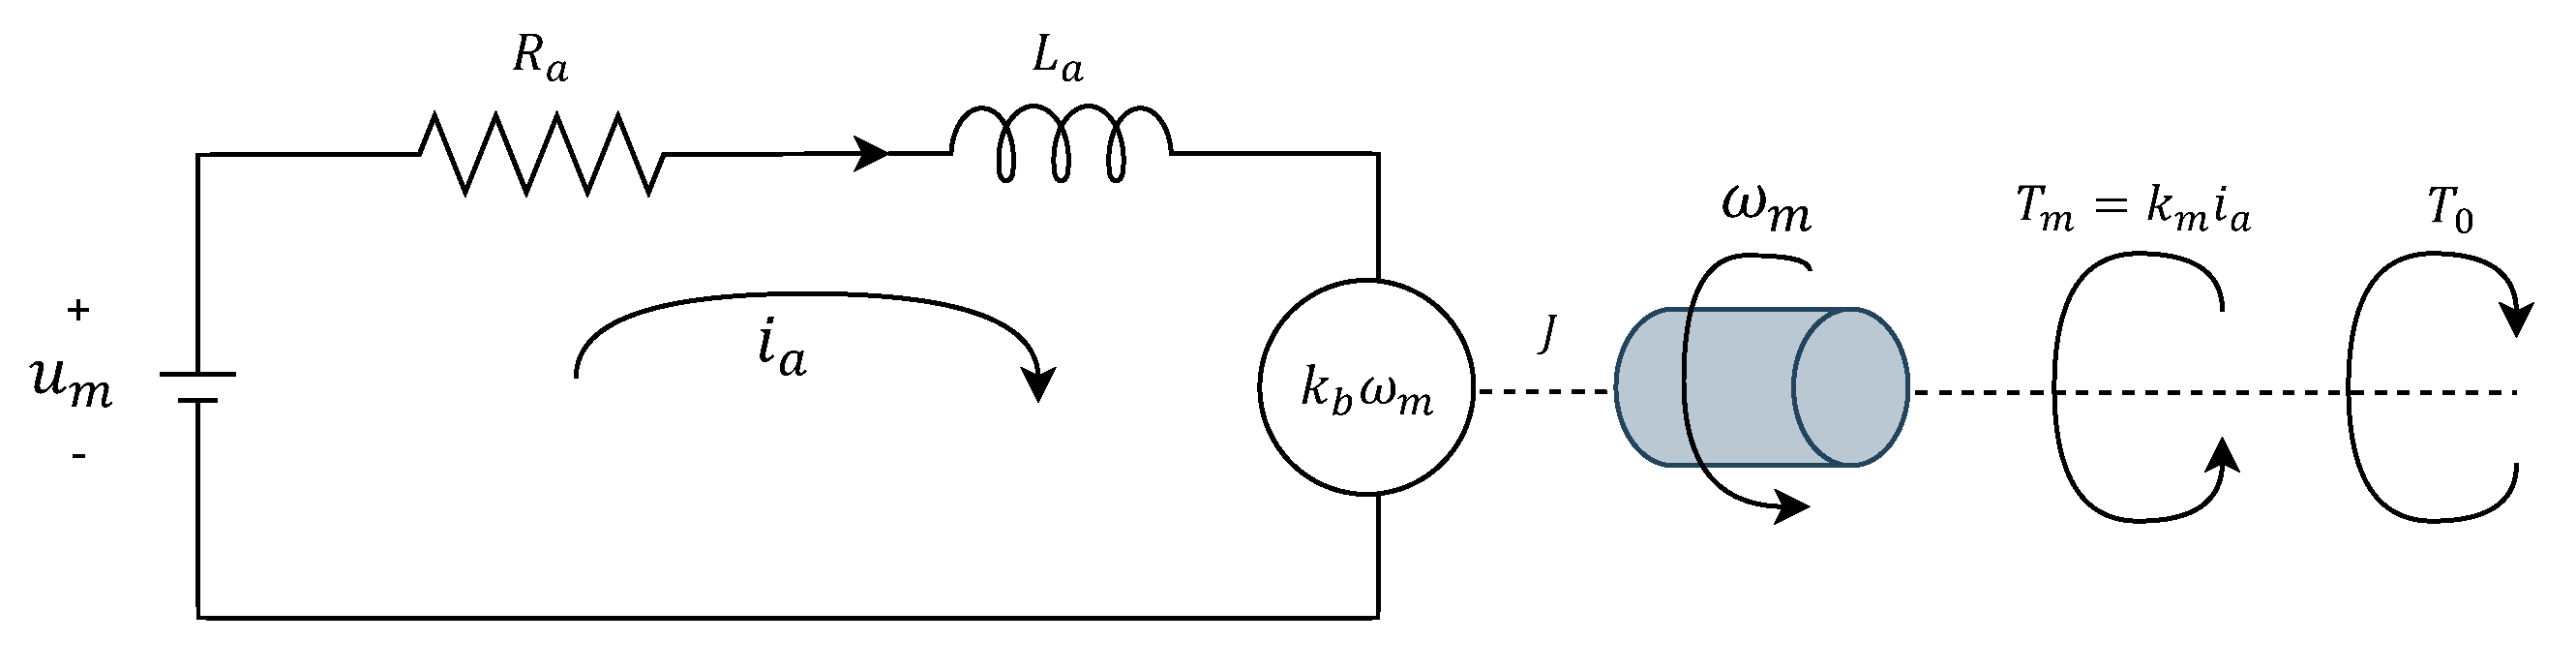
The electromechanical diagram of the DC Motor is presented in Figure 4, where corresponds to the voltage applied to generate motion; and represent the position and angular velocity, respectively; denotes the motor armature current; and corresponds to a torque disturbance. The dynamic model of the DC motor was obtained from [27,28] and is described in Equation (24). The numerical values and units of the motor parameters are shown in Table 1, which were taken from [28].
Figure 4.
DC Motor model.
Table 1.
DC Motor Parameters.
3.6. Description of the Dynamic Model of the Buck Type DC-DC Converter
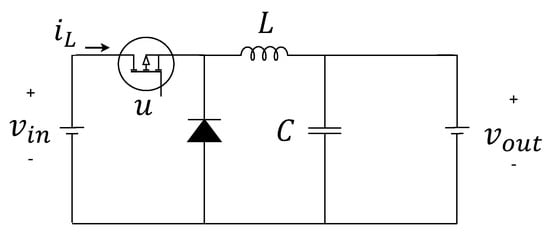
The electrical diagram of the Buck DC-DC converter is shown in Figure 5, where u corresponds to the control signal or pulse-width modulated signal applied to the switching device; represents the inductor current, and denotes the converter output voltage. The dynamic model of the Buck converter was obtained from [27,29] and is described in Equation (25). The numerical values and units of the system parameters are presented in Table 2, which were taken from [27].
Figure 5.
Buck converter model.
Table 2.
Buck Converter Parameters.
3.7. Description of the IPOC Dynamic Model
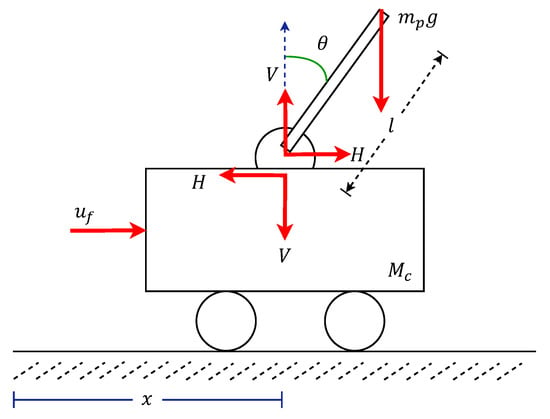
Figure 6 shows the free-body diagram of the IPOC. In this model, corresponds to the force applied to the cart to generate the motion; represents the angle of the pendulum, measured in radians concerning the vertical; and denotes the position of the cart in meters. The dynamic model of the IPOC was obtained from [30] and is expressed in Equation (26). The numerical values and units of the parameters used in the model are shown in Table 3, which were taken from [30].
Figure 6.
IPOC free body diagram.
Table 3.
IPOC Parameters.
3.8. ANN’s Performance as a Regulator
Once the dynamic model has been analyzed and the parameters of the proposed systems have been obtained, as well as the hardware for the implementation of the neural network (Equations (4)–(7)) and the learning algorithm (Equations (10) and (11)) having been described in Verilog hardware description language, a cosimulation is performed using the Simulink software environments of MATLAB R2025a and ModelSim 2024.4. In this cosimulation, the behavior of the neural network as a regulator is applied to the dynamic systems described in Equations (24)–(26), and the resulting behavior is observed.
3.8.1. Description of the Test with the DC Motor
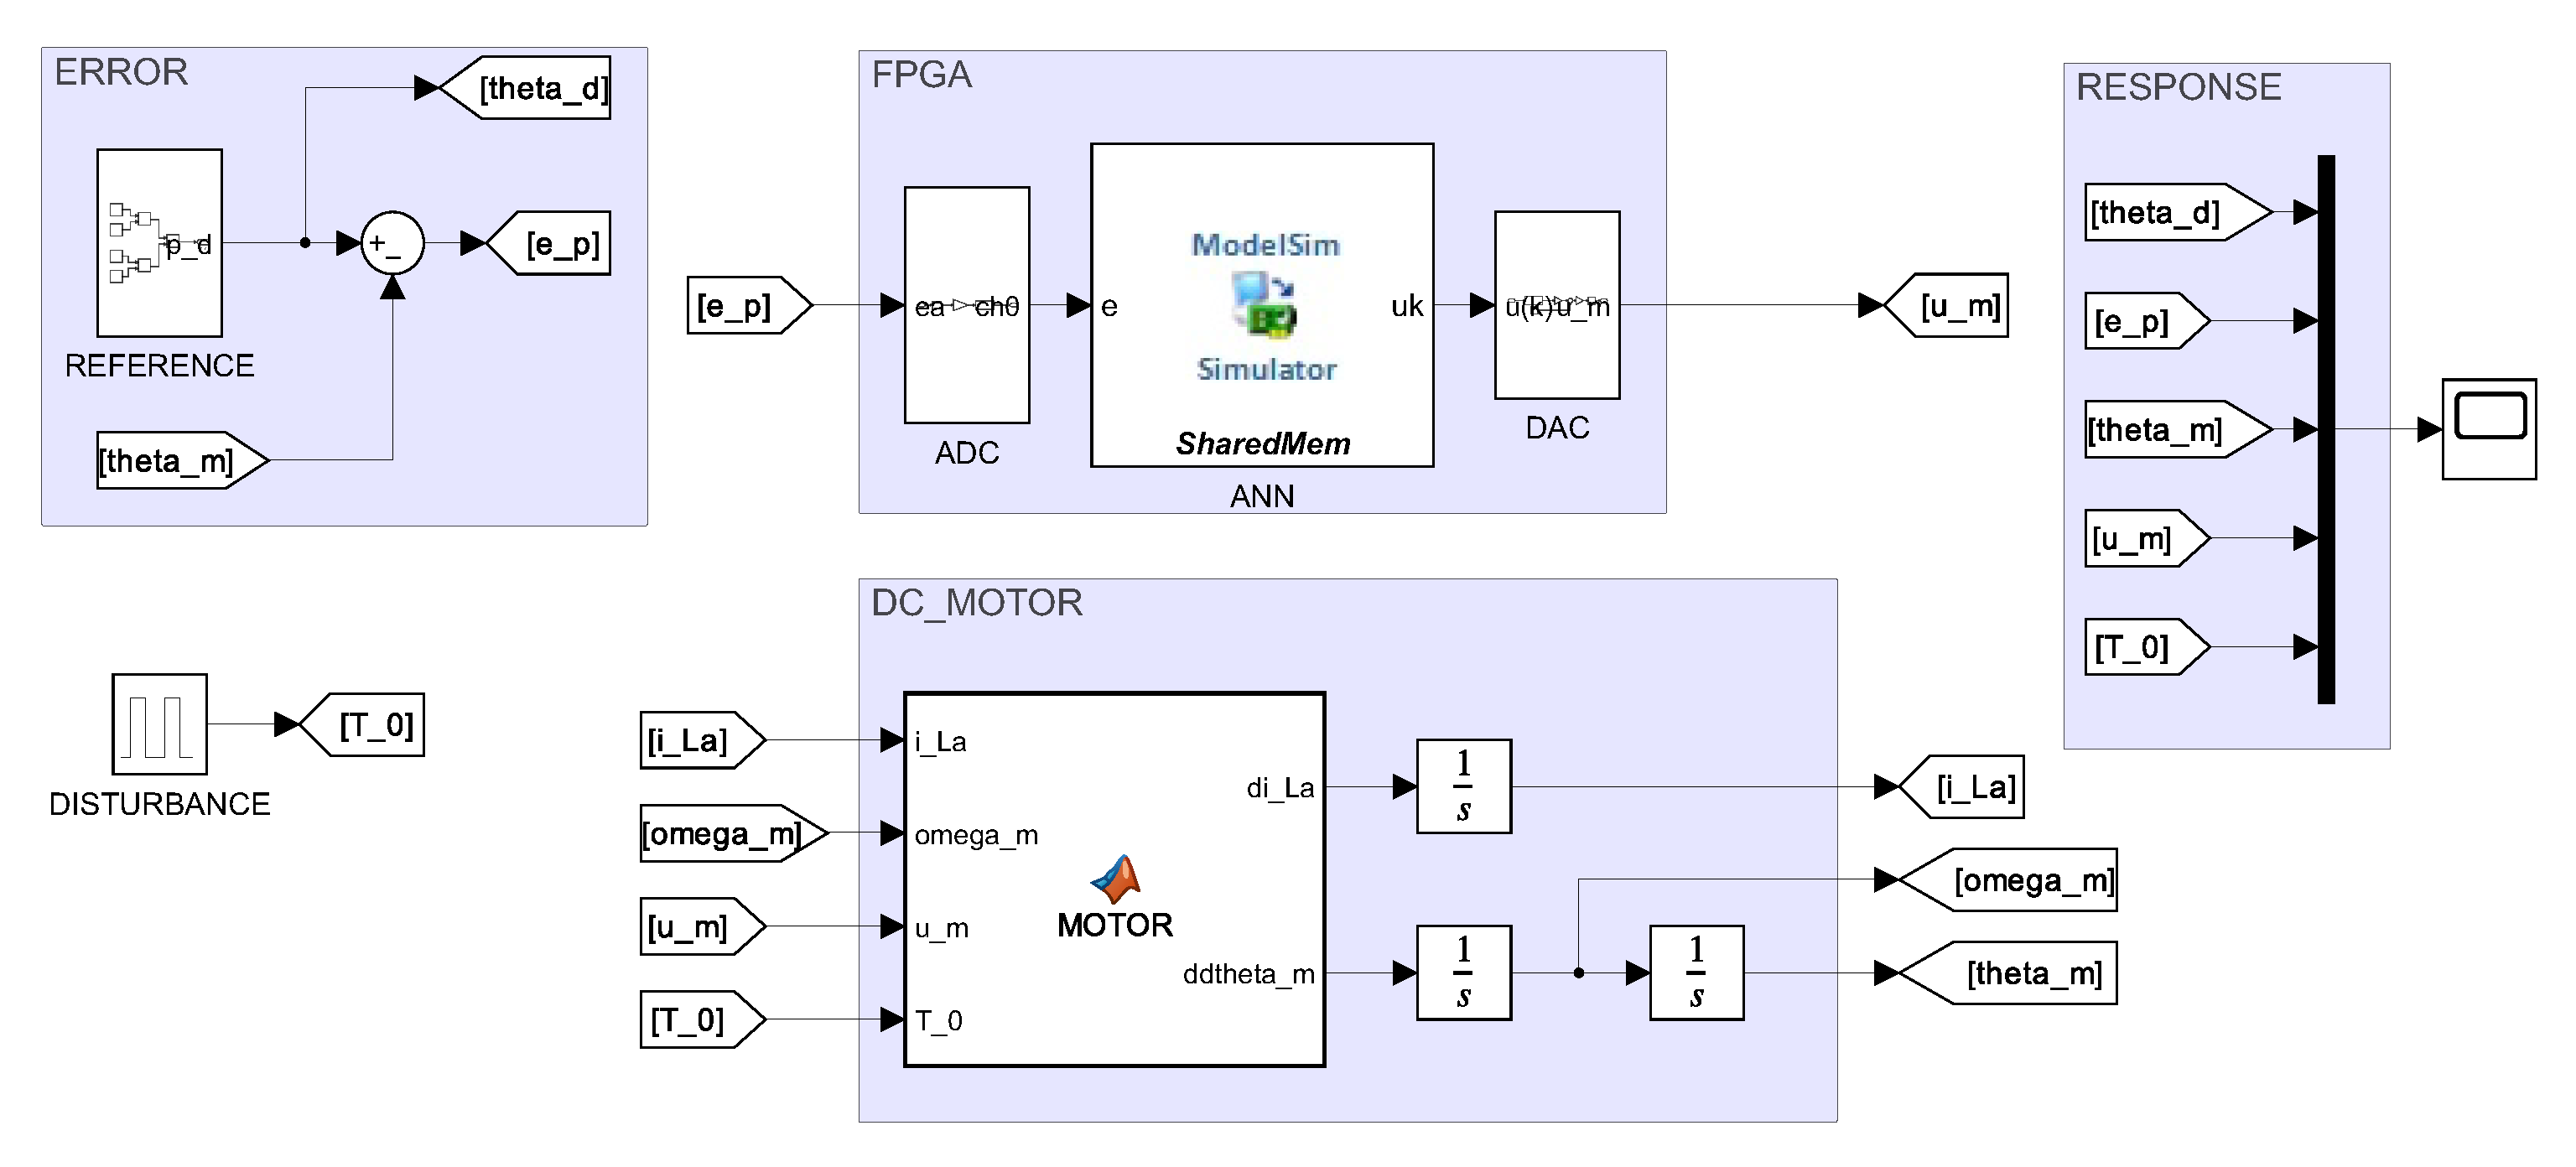
In Figure 7, the scheme used to regulate the angular position of the direct current motor is presented, which is divided into four main blocks. The first block, named ERROR, corresponds to the calculation of the error signal from a reference composed of step inputs with magnitudes , , 0, , , and 0 radians, which change every 5 s. The second block, named DC_MOTOR, implements the dynamics described in Equation (24), considering the parameters listed in Table 1. The third block, named FPGA, contains the Verilog code of the neural network and the learning algorithm, configured with three inputs, one hidden layer with three neurons, and one output neuron. Finally, sigmoid functions were used as activation functions for both the hidden-layer neurons and the output neuron. The learning coefficient used for this system was . The input layer weights () were initialized to zero, for the output layer weights () the values were initialized randomly, however the values used for the implementation in verilog are , since with these values the ANN reached a zero steady-state error in less time, according to the tests performed.
Figure 7.
Cosimulation for neural control of DC motor.
Finally, block 4, called RESPONSE, is responsible for extracting the relevant variables from the system, such as the desired angular position , the position error , the angular position of the motor , the control signal or output of the neural network and the disturbance , which is introduced to the system in the form of pulses with an amplitude of , presented every 5 s with a delay of 3 s.
3.8.2. Buck DC-DC Converter Test Description
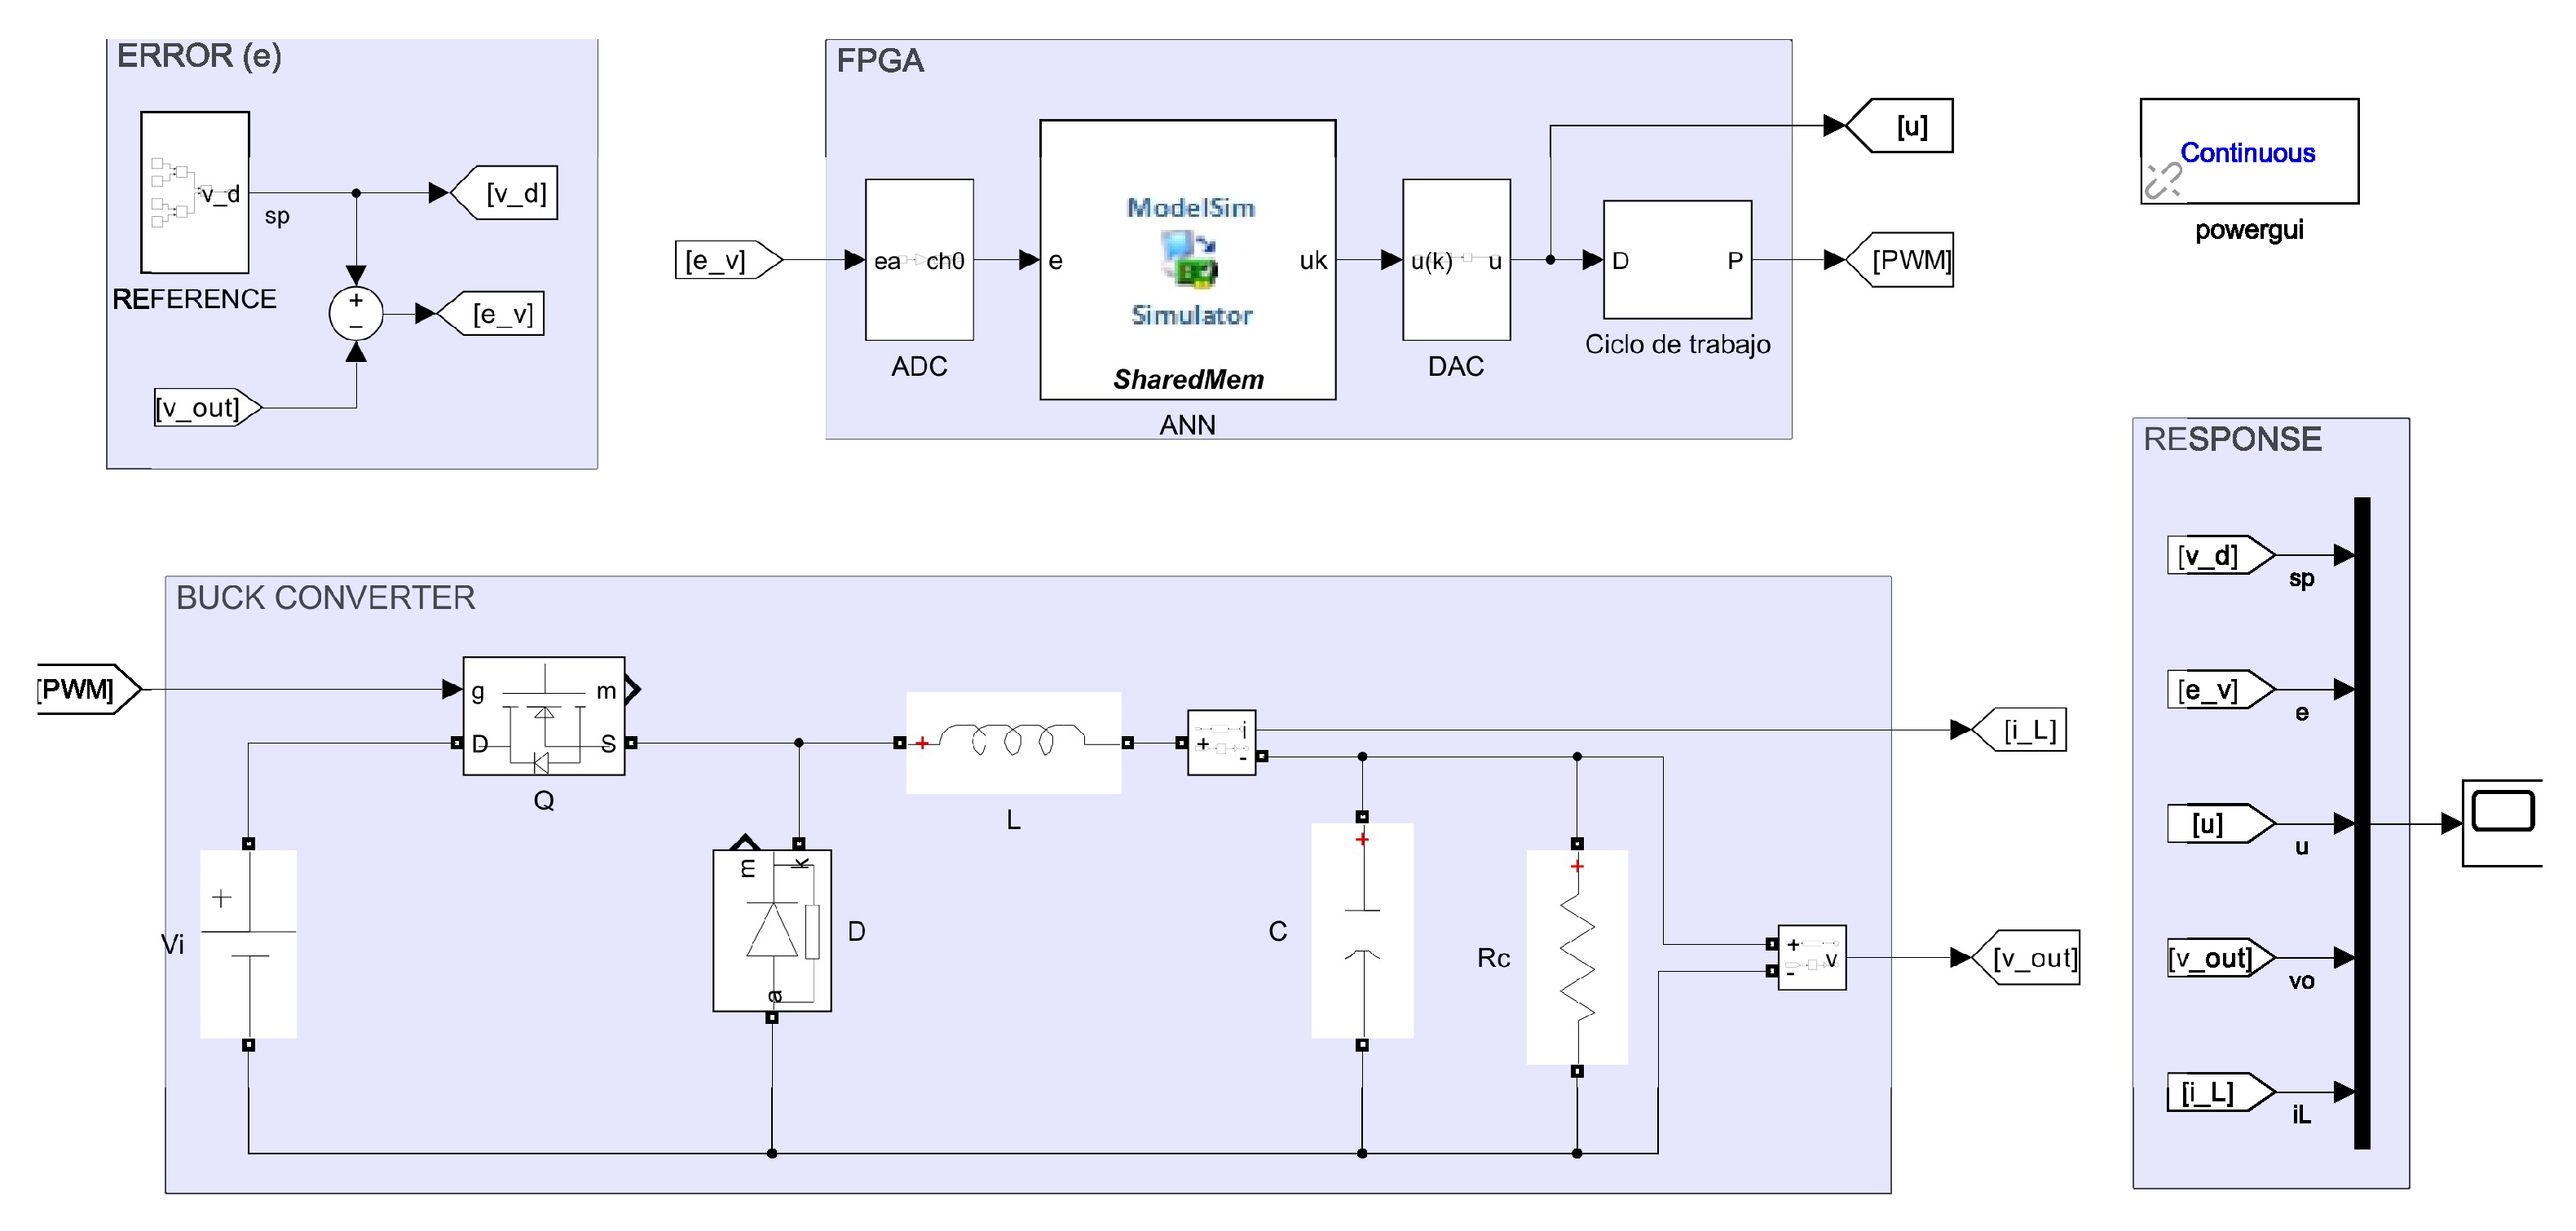
Figure 8 illustrates the scheme employed to regulate the output voltage of the Buck-type DC-DC converter, which is divided into four blocks. The first block, referred to as ERROR, corresponds to the computation of the error when applying a step reference with magnitudes of 24, 15, and 10 volts, changing every 50 ms. The second block, named BUCK_CONVERTER, implements Equation (25) using the parameters listed in Table 2. The FPGA block integrates the Verilog code of the neural network along with the learning algorithm, configured identically to the neural network described previously. The learning coefficient used was . The input layer weights () were initialized to zero, for the output layer weights () the values were initialized randomly, however the values used for the Verilog implementation are , since with these values the ANN reached zero steady-state error in less time, according to the tests performed.
Figure 8.
Cosimulation for neural control of the Buck converter.
Block 4, called RESPONSE, is responsible for extracting the relevant variables from the system, including the desired output voltage , the error , the converter output voltage , the control signal or neural network output u, the inductor current .
3.8.3. Description of the Test with the IPOC
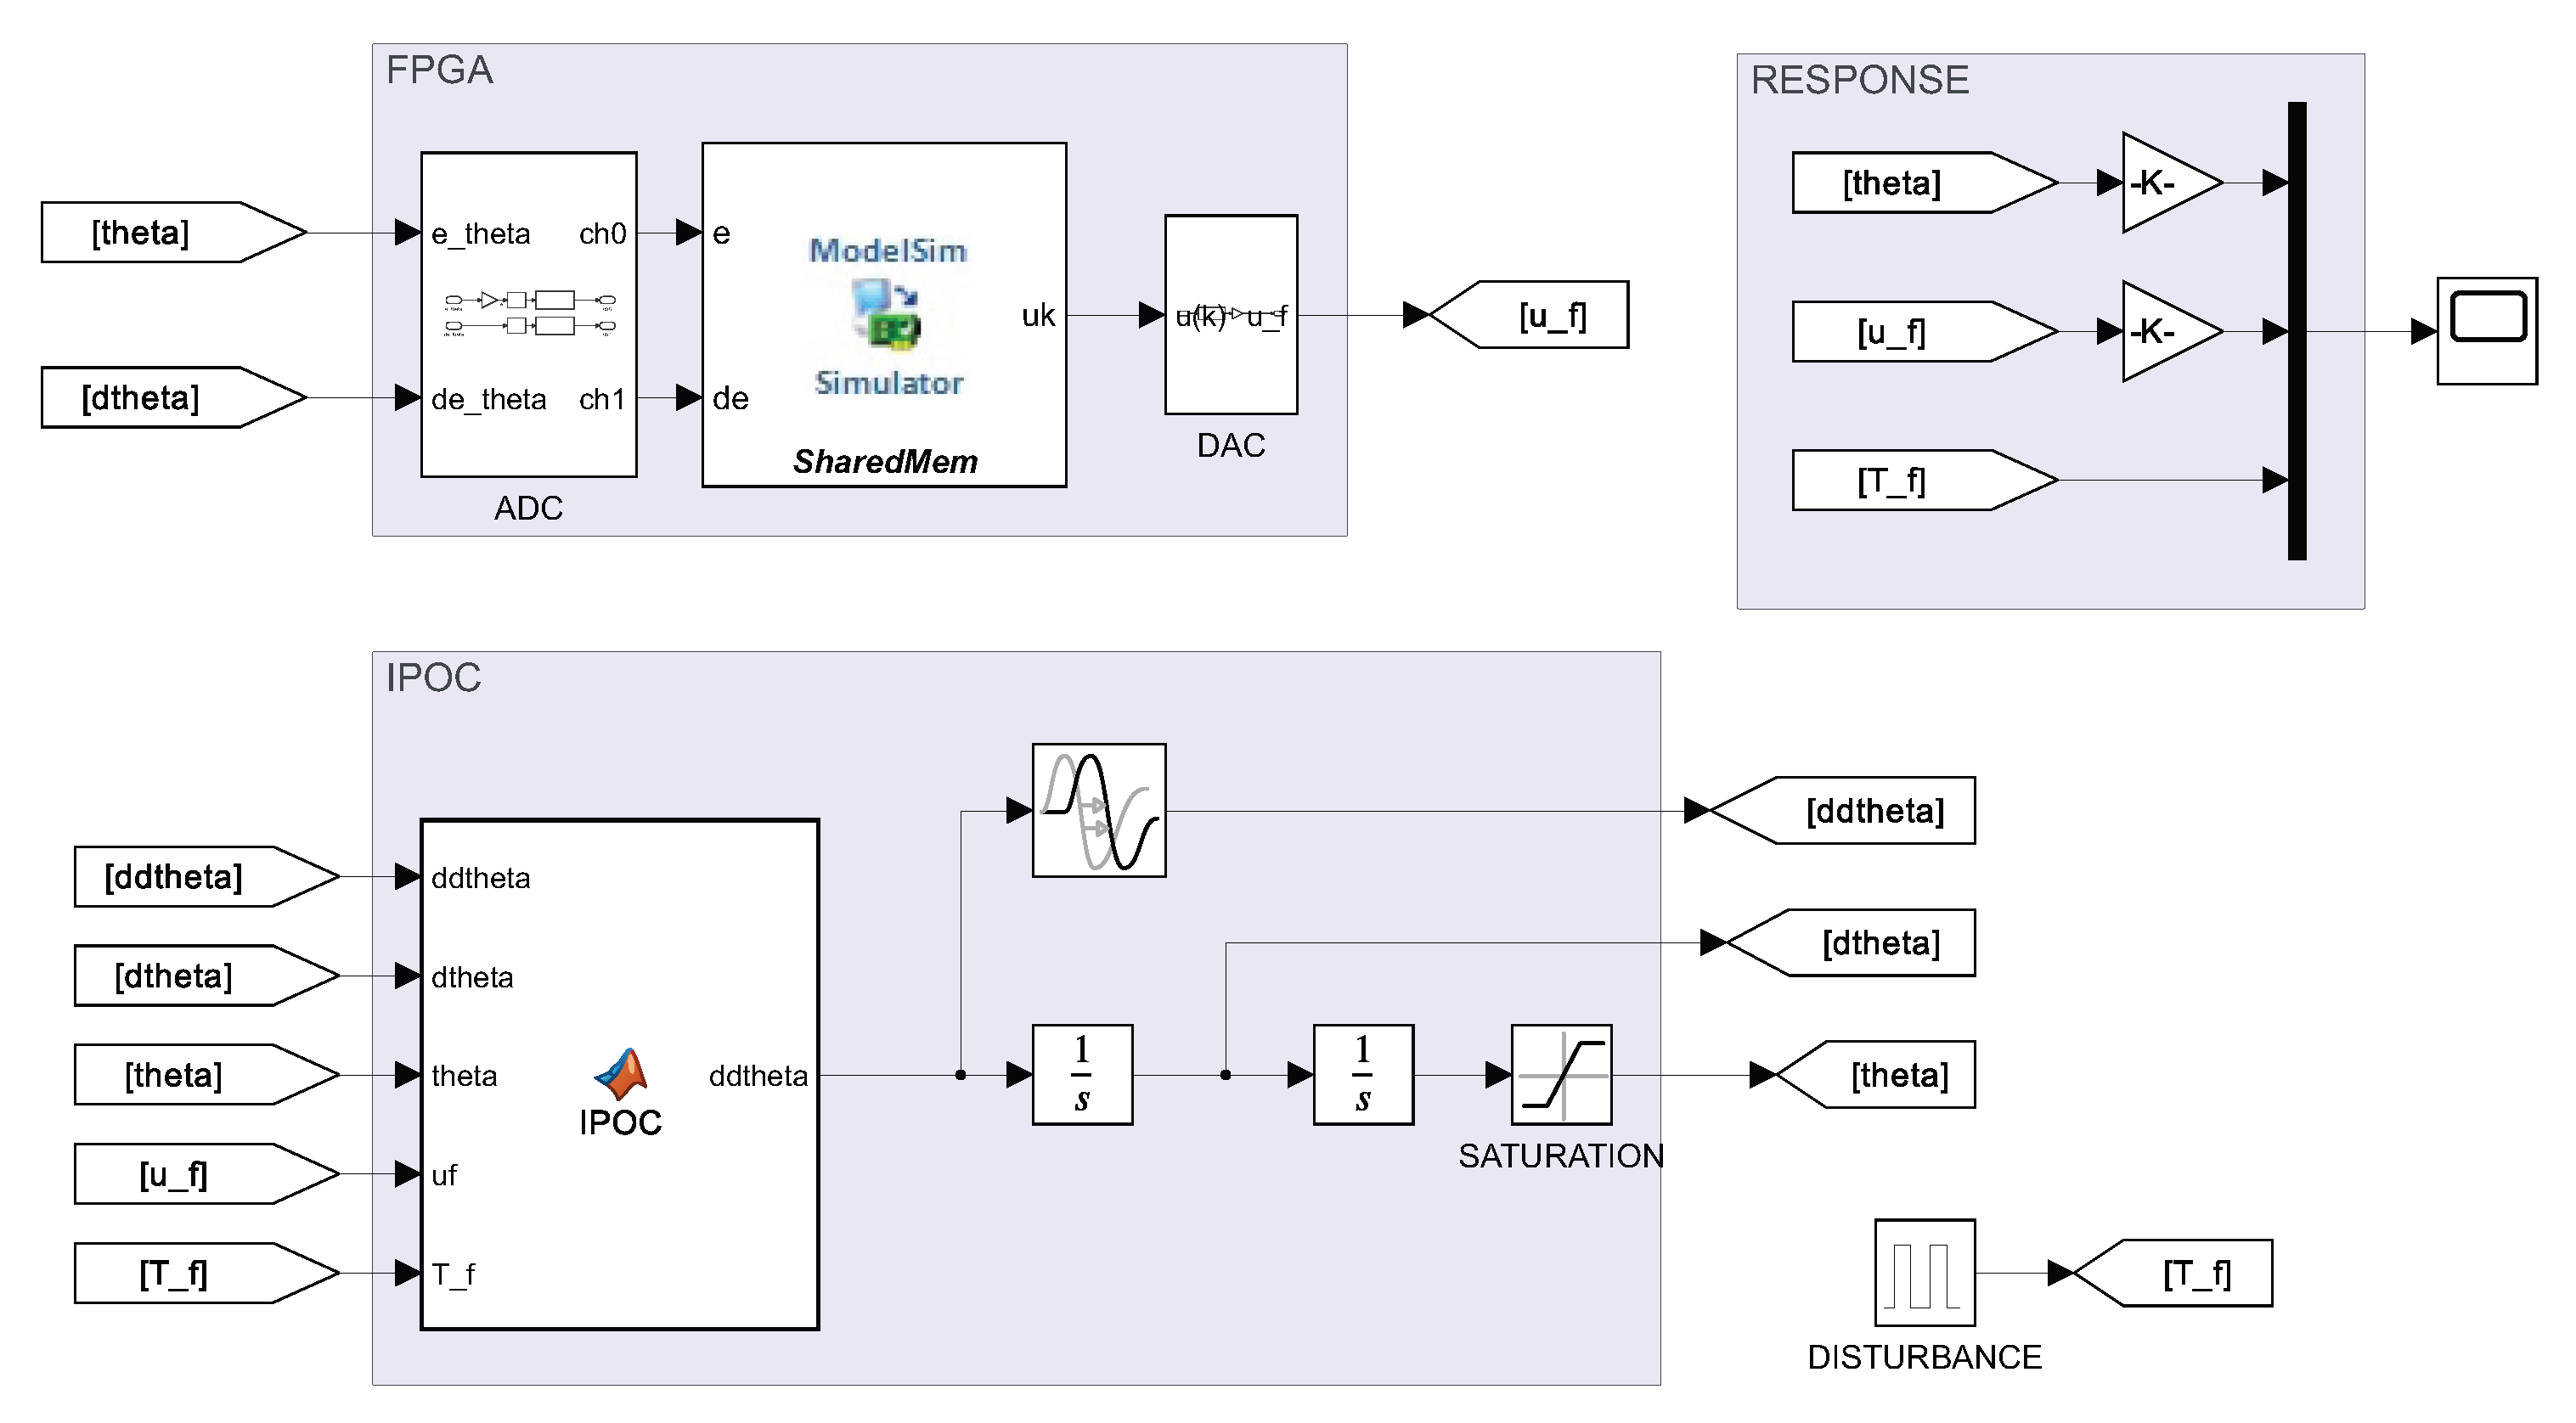
Figure 9 presents the scheme used to ensure that the pendulum remains in a vertical position, that is, stabilized at . This scheme is organized into three blocks. The first block, called IPOC, describes Equation (26) along with the parameters shown in Table 3. The second block, called FPGA, implements the neural network and learning algorithm in Verilog, configured with 12 inputs, a hidden layer comprising 10 neurons, and an output layer with one neuron. For the neurons in the hidden layer, the hyperbolic tangent activation function (Equation (27)) was used, while a linear function was used in the output layer. Finally, the learning algorithm that allows the updating of the weights of each neuron, described in Equations (10) and (11), is updated according to the expressions shown in Equations (28) and (29), respectively.
Figure 9.
Cosimulation for the neural control of the Inverted Pendulum on a Car.
The learning coefficient used was . The input layer weights () were initialized to zero, for the output layer weights () the values were initialized randomly, however the values used for the implementation in verilog are (–0.597, –0.975, 0.682, 0.526, –0.404, 0.249, –0.947, –0.945, –0.287, –0.720), since with these values the ANN reached a zero steady-state error in less time, according to the tests performed.
Block 3, called RESPONSE, is responsible for extracting the relevant variables from the system: the angular position of the pendulum , the control signal or output of the neural network , and the disturbance , which is introduced to the system in the form of pulses with an amplitude of . These pulses are applied every 10 s, with an initial delay of 2.5 s.
4. Results
Results of the ANN Design
As mentioned above, the main objective is to implement an ANN as a dynamic systems regulator in FPGAs that do not have a large logic density. To validate the proposal, tests were performed on three FPGA devices. The first corresponds to the ICE40UP5K model from the Lattice family, for which the YosysHQ synthesizer from the ICESTORM project [31] was used. The other two devices used were the XC3S200A (Spartan 3) and the XC6SLX4 (Spartan 6), both from Xilinx, which were synthesized using ISE 14.7 software.
Table 4 shows the logic resources used in the design of the ANN implemented as a regulator, under the structure proposed in Figure 2.
Table 4.
Logical resources of the proposed implementation.
Figure 10 presents the system variables: , which corresponds to the desired angular position of the motor shaft; , which represents the controlled variable; , which denotes the position error of the DC motor and integrates the ANN input; and , which corresponds to the perturbation applied to the system. Likewise, represents the ANN output or control signal.
Figure 10.
DC motor cosimulation results.
It can be observed that the ANN, when regulating a linear and stable system, achieves a practically perfect response to changes in the reference through both positive and negative steps. For this system, the ANN calculations—both the control signal and the learning algorithm for updating the weights—were performed every 1 ms. As the learning process progresses, it becomes apparent that the overshoot progressively decreases. Another relevant aspect is that the control signal does not present saturation, always remaining within the established limits of V.
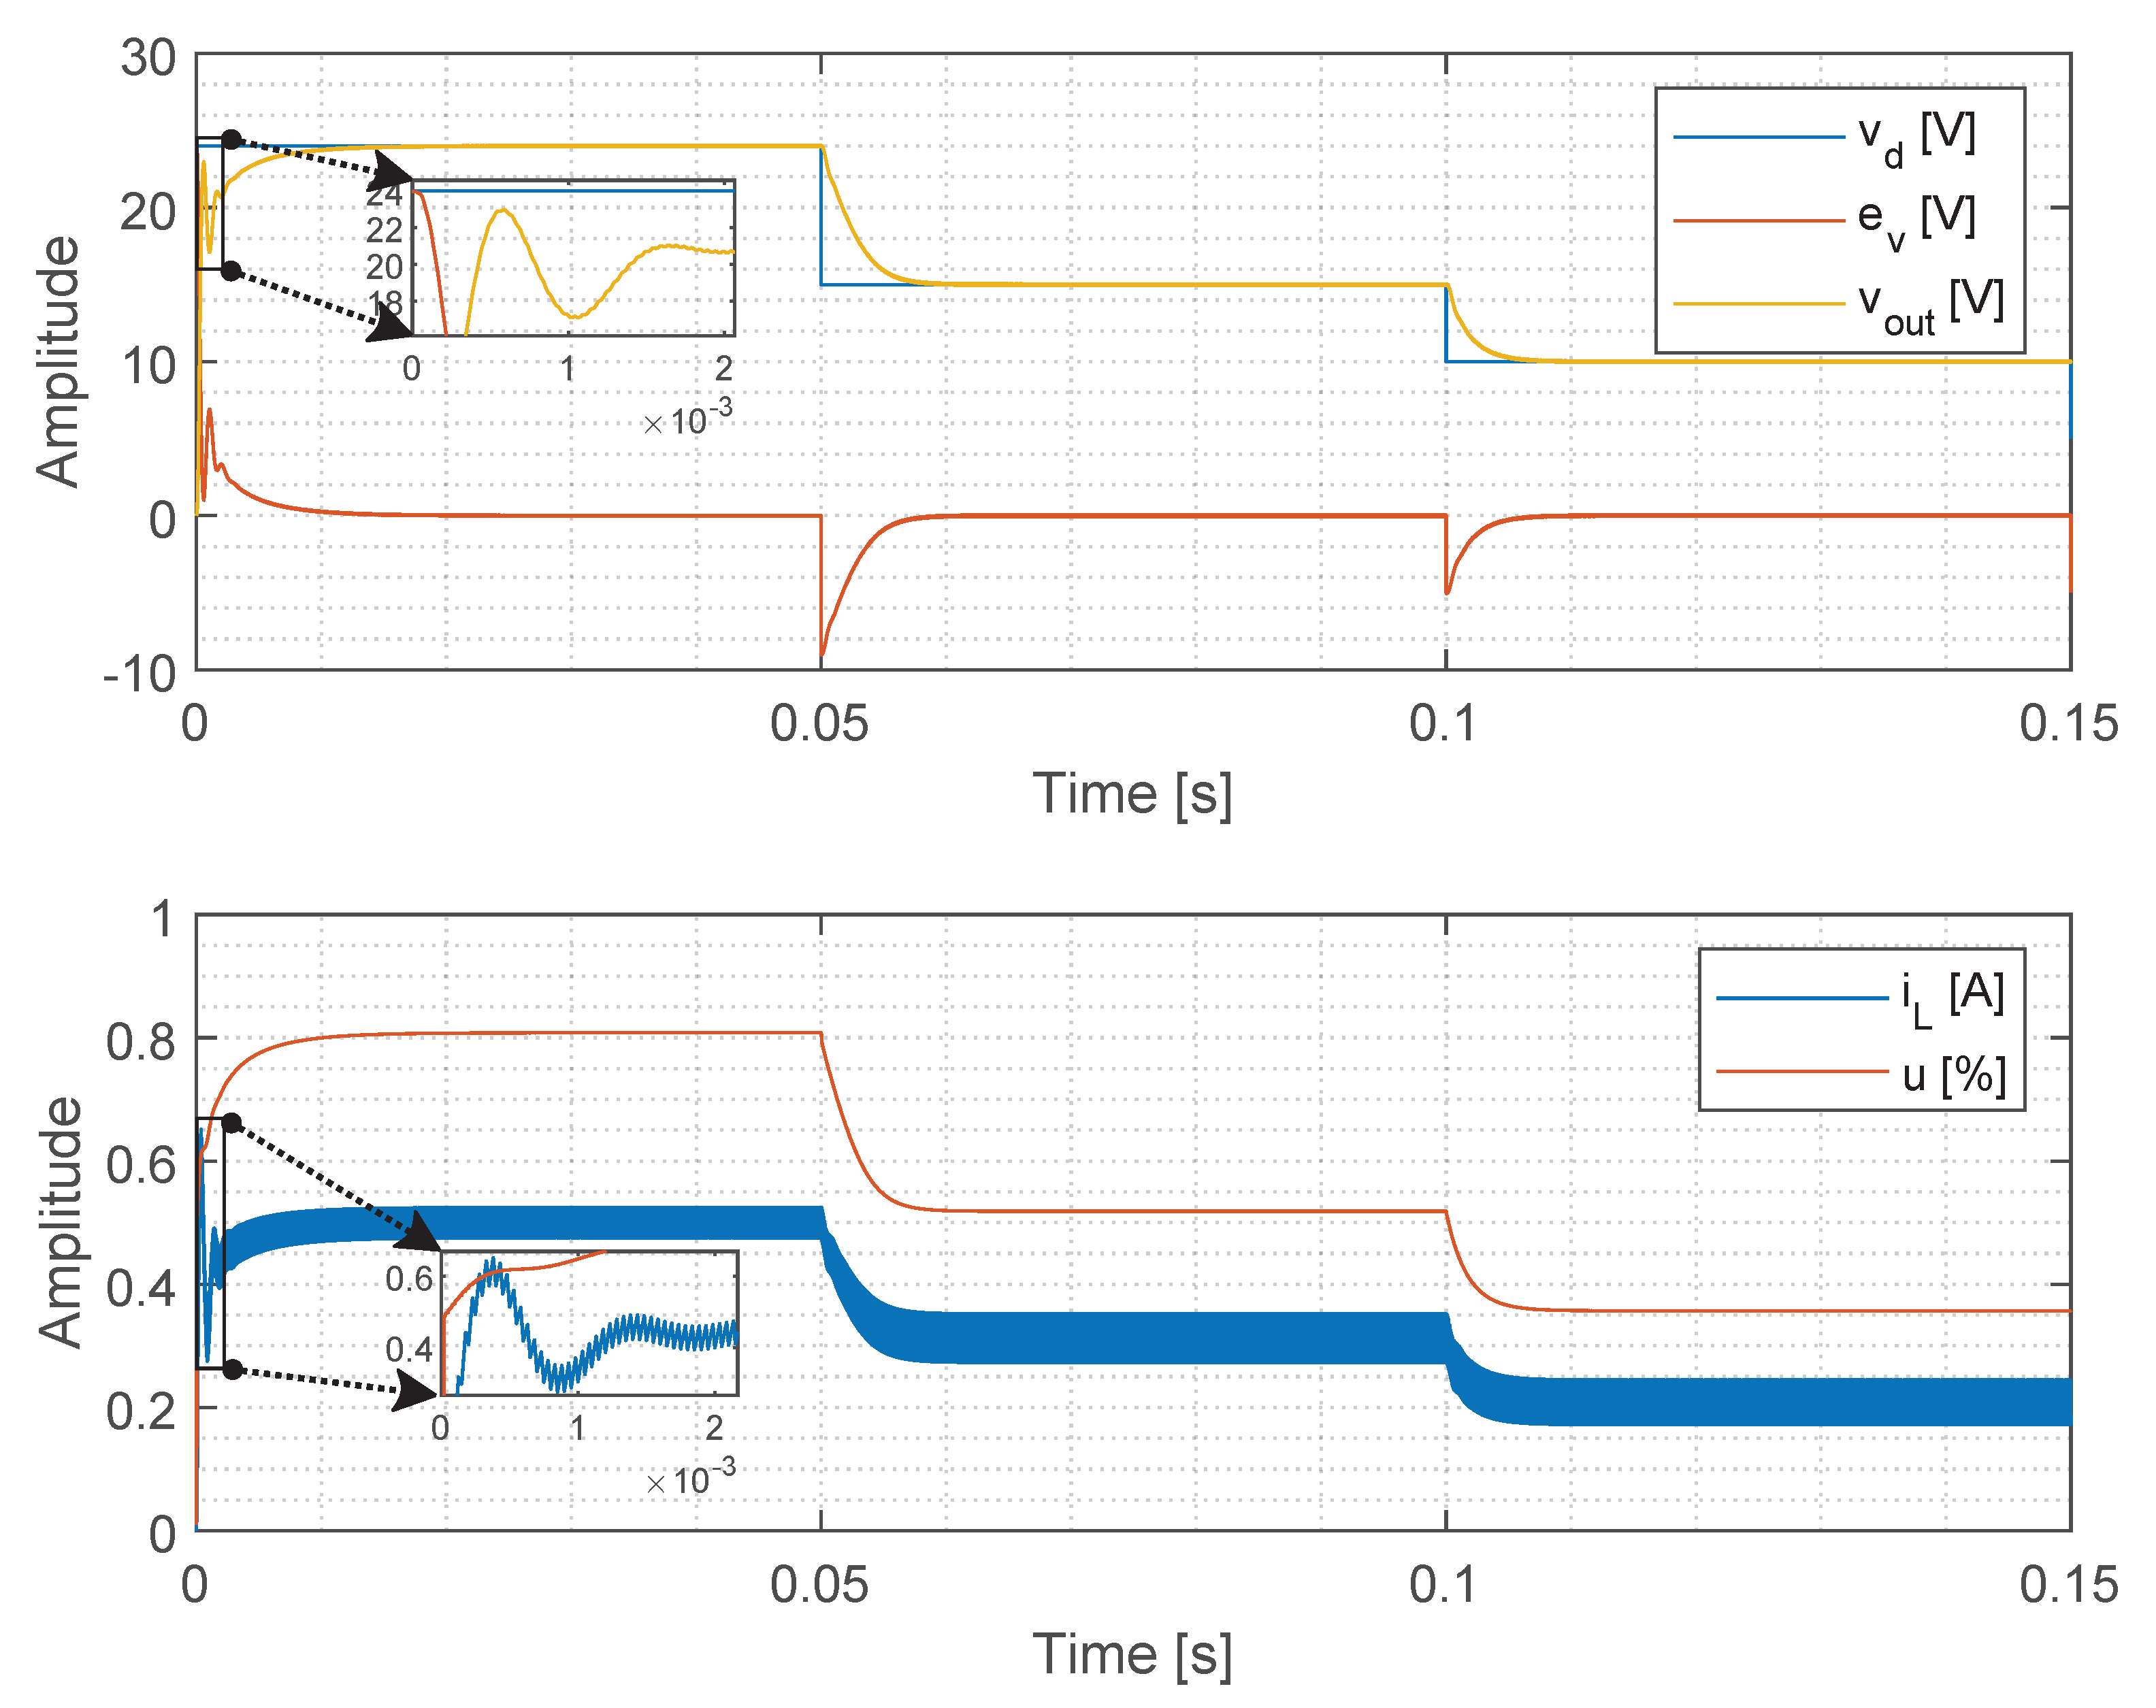
For the tests performed in Figure 11, the ANN used a sampling time of 10 μs to calculate the control signal and the learning algorithm to update the weights. Likewise, the variables are shown, which represent the desired voltage output at the load, is the controlled variable, and is the voltage error, the input to the ANN. and are the perturbation applied to the system and the current in the inductor, respectively. The ANN output or control signal is represented by u. It is observed that the ANN, when regulating a nonlinear and stable system, achieves a practically perfect response when applying changes to the reference, regardless of the perturbation applied.
Figure 11.
Buck converter cosimulation results.
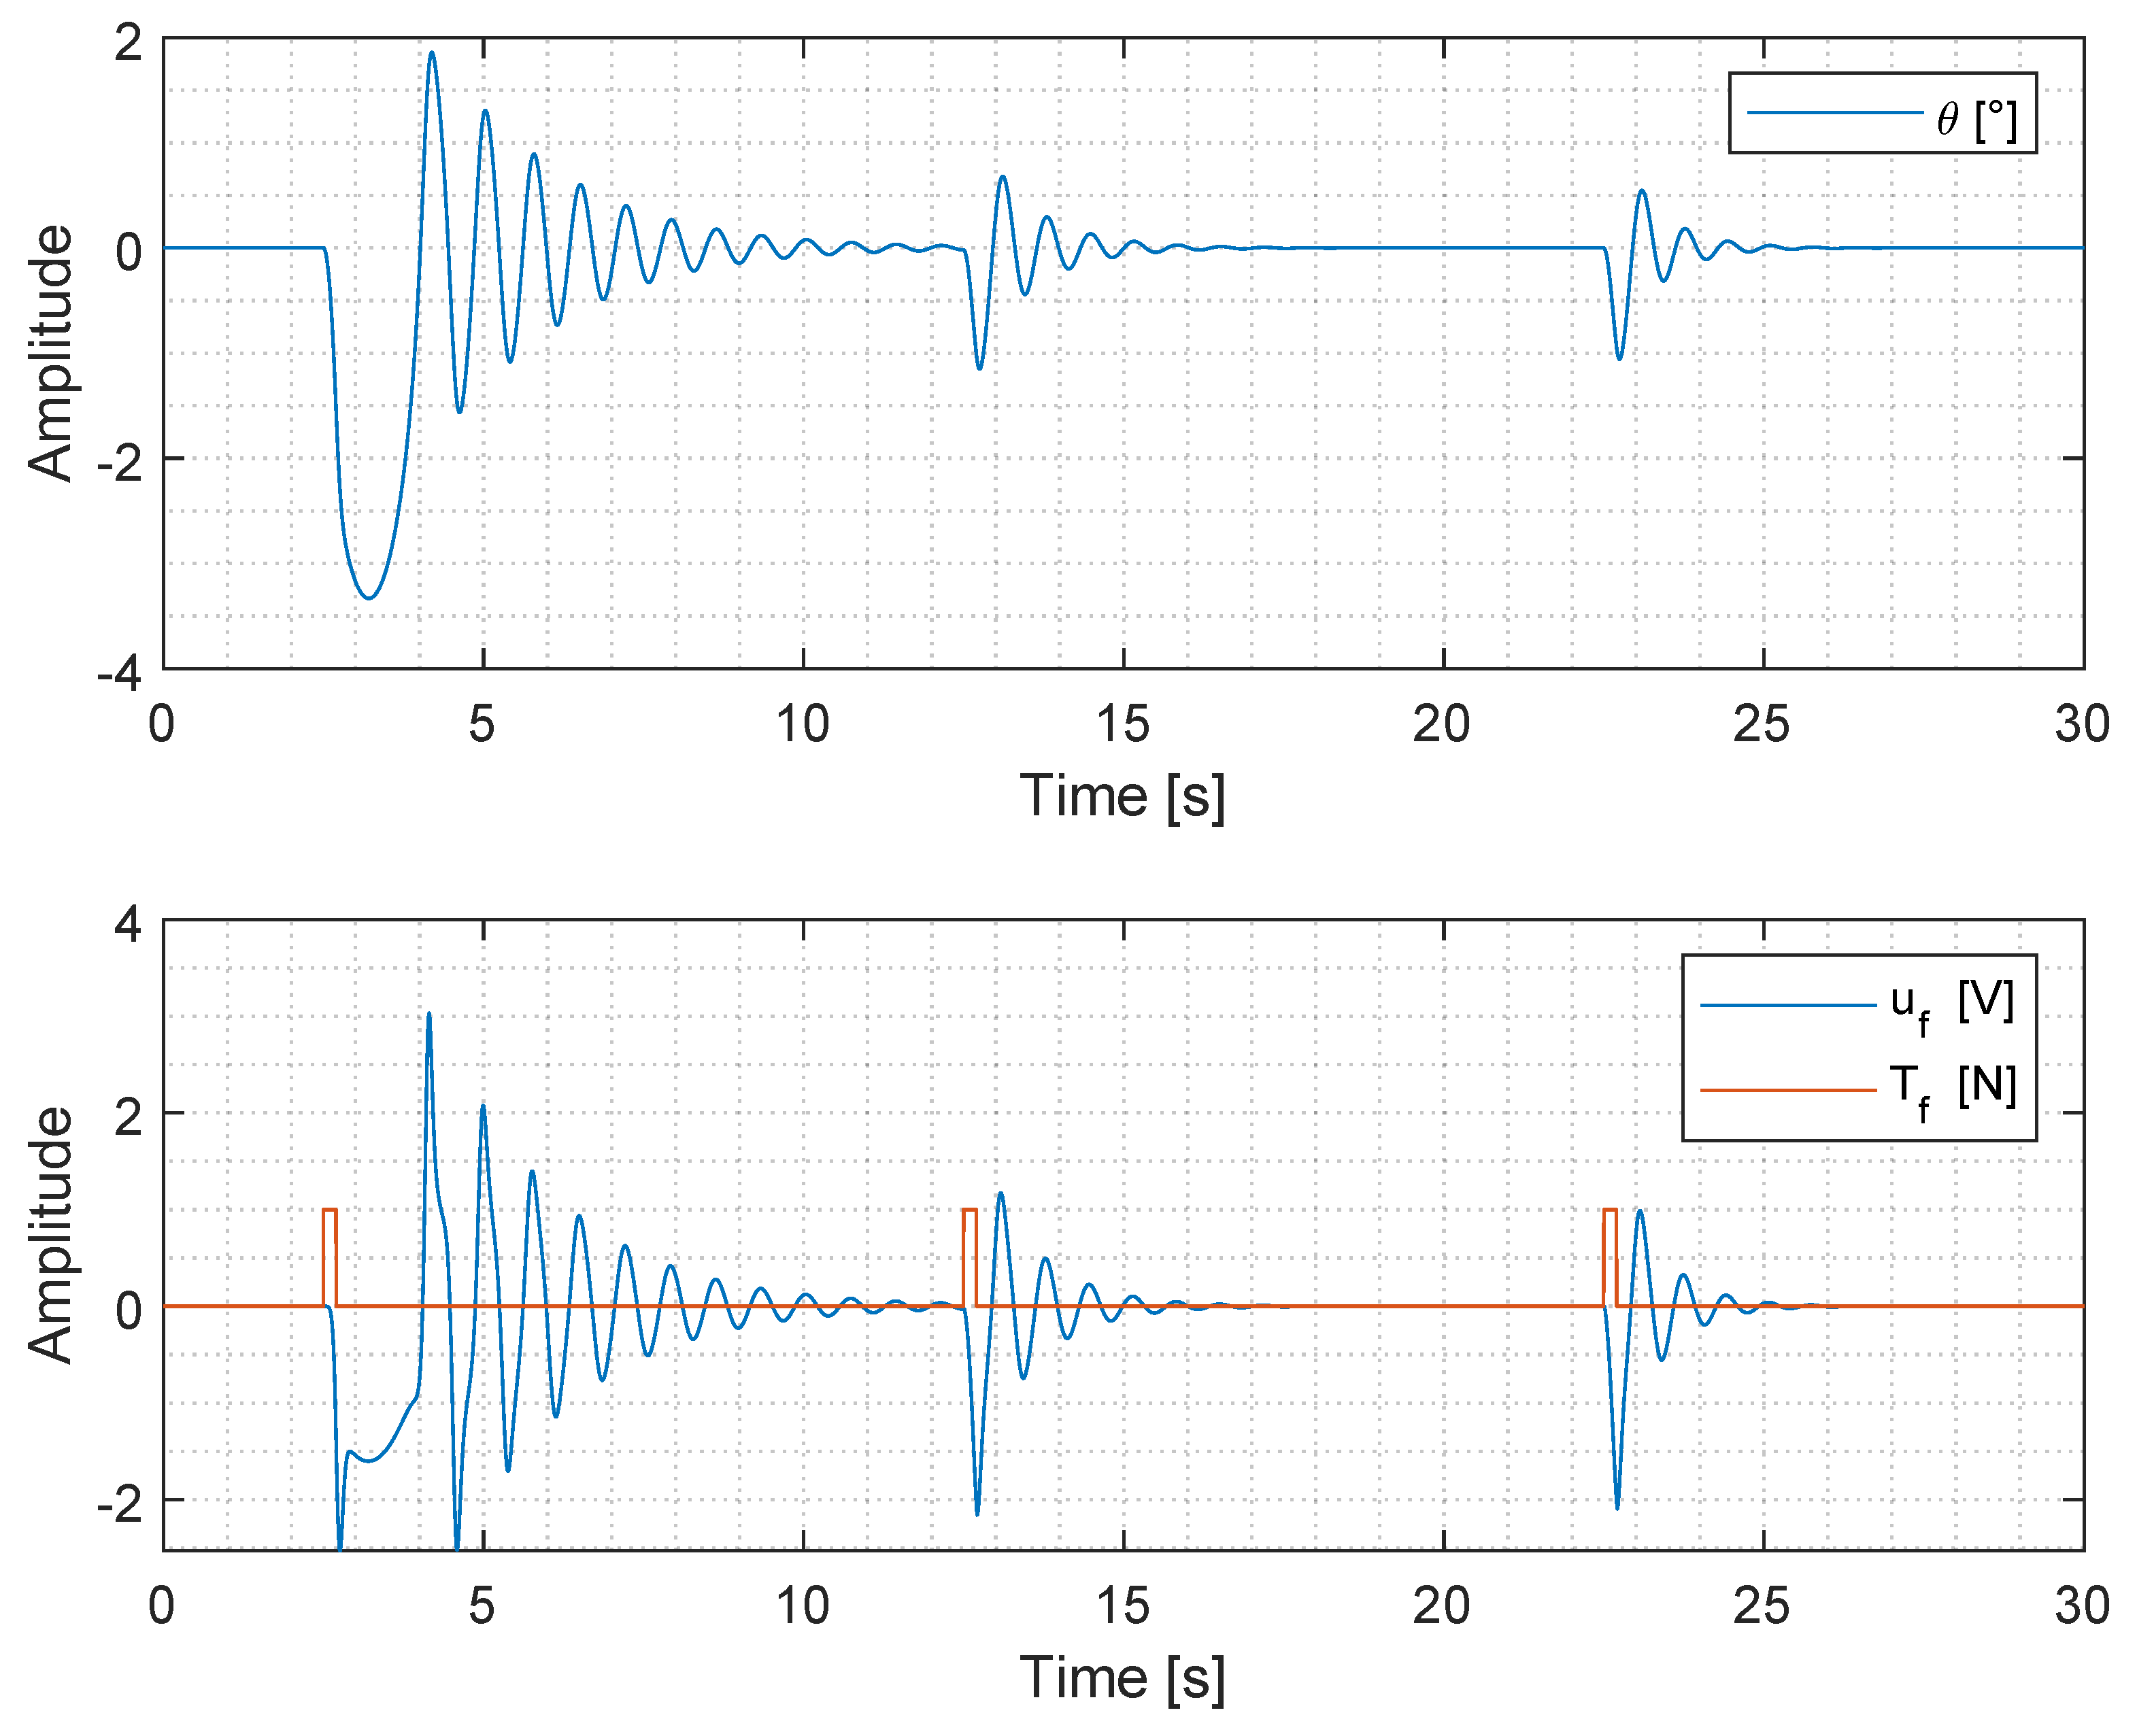
Finally, Figure 12 shows the results obtained by applying the ANN as a regulator to keep the inverted pendulum vertically on a cart. A sampling time of 5 ms was applied to calculate the control signal and update the ANN weights using the learning algorithm. The variables , which represent the controlled variable, are shown. is the perturbation applied to the system, and the ANN output or control signal is represented by u. As can be seen, the ANN is regulating a nonlinear and unstable system, which is difficult to control with conventional control techniques. It is also observed that as the system learns, the oscillations and overshoot of the controlled signal decrease, and the system settling time is less than 4 s. Therefore, according to the system characteristics, a response considered good is obtained.
Figure 12.
IPOC co-simulation results.
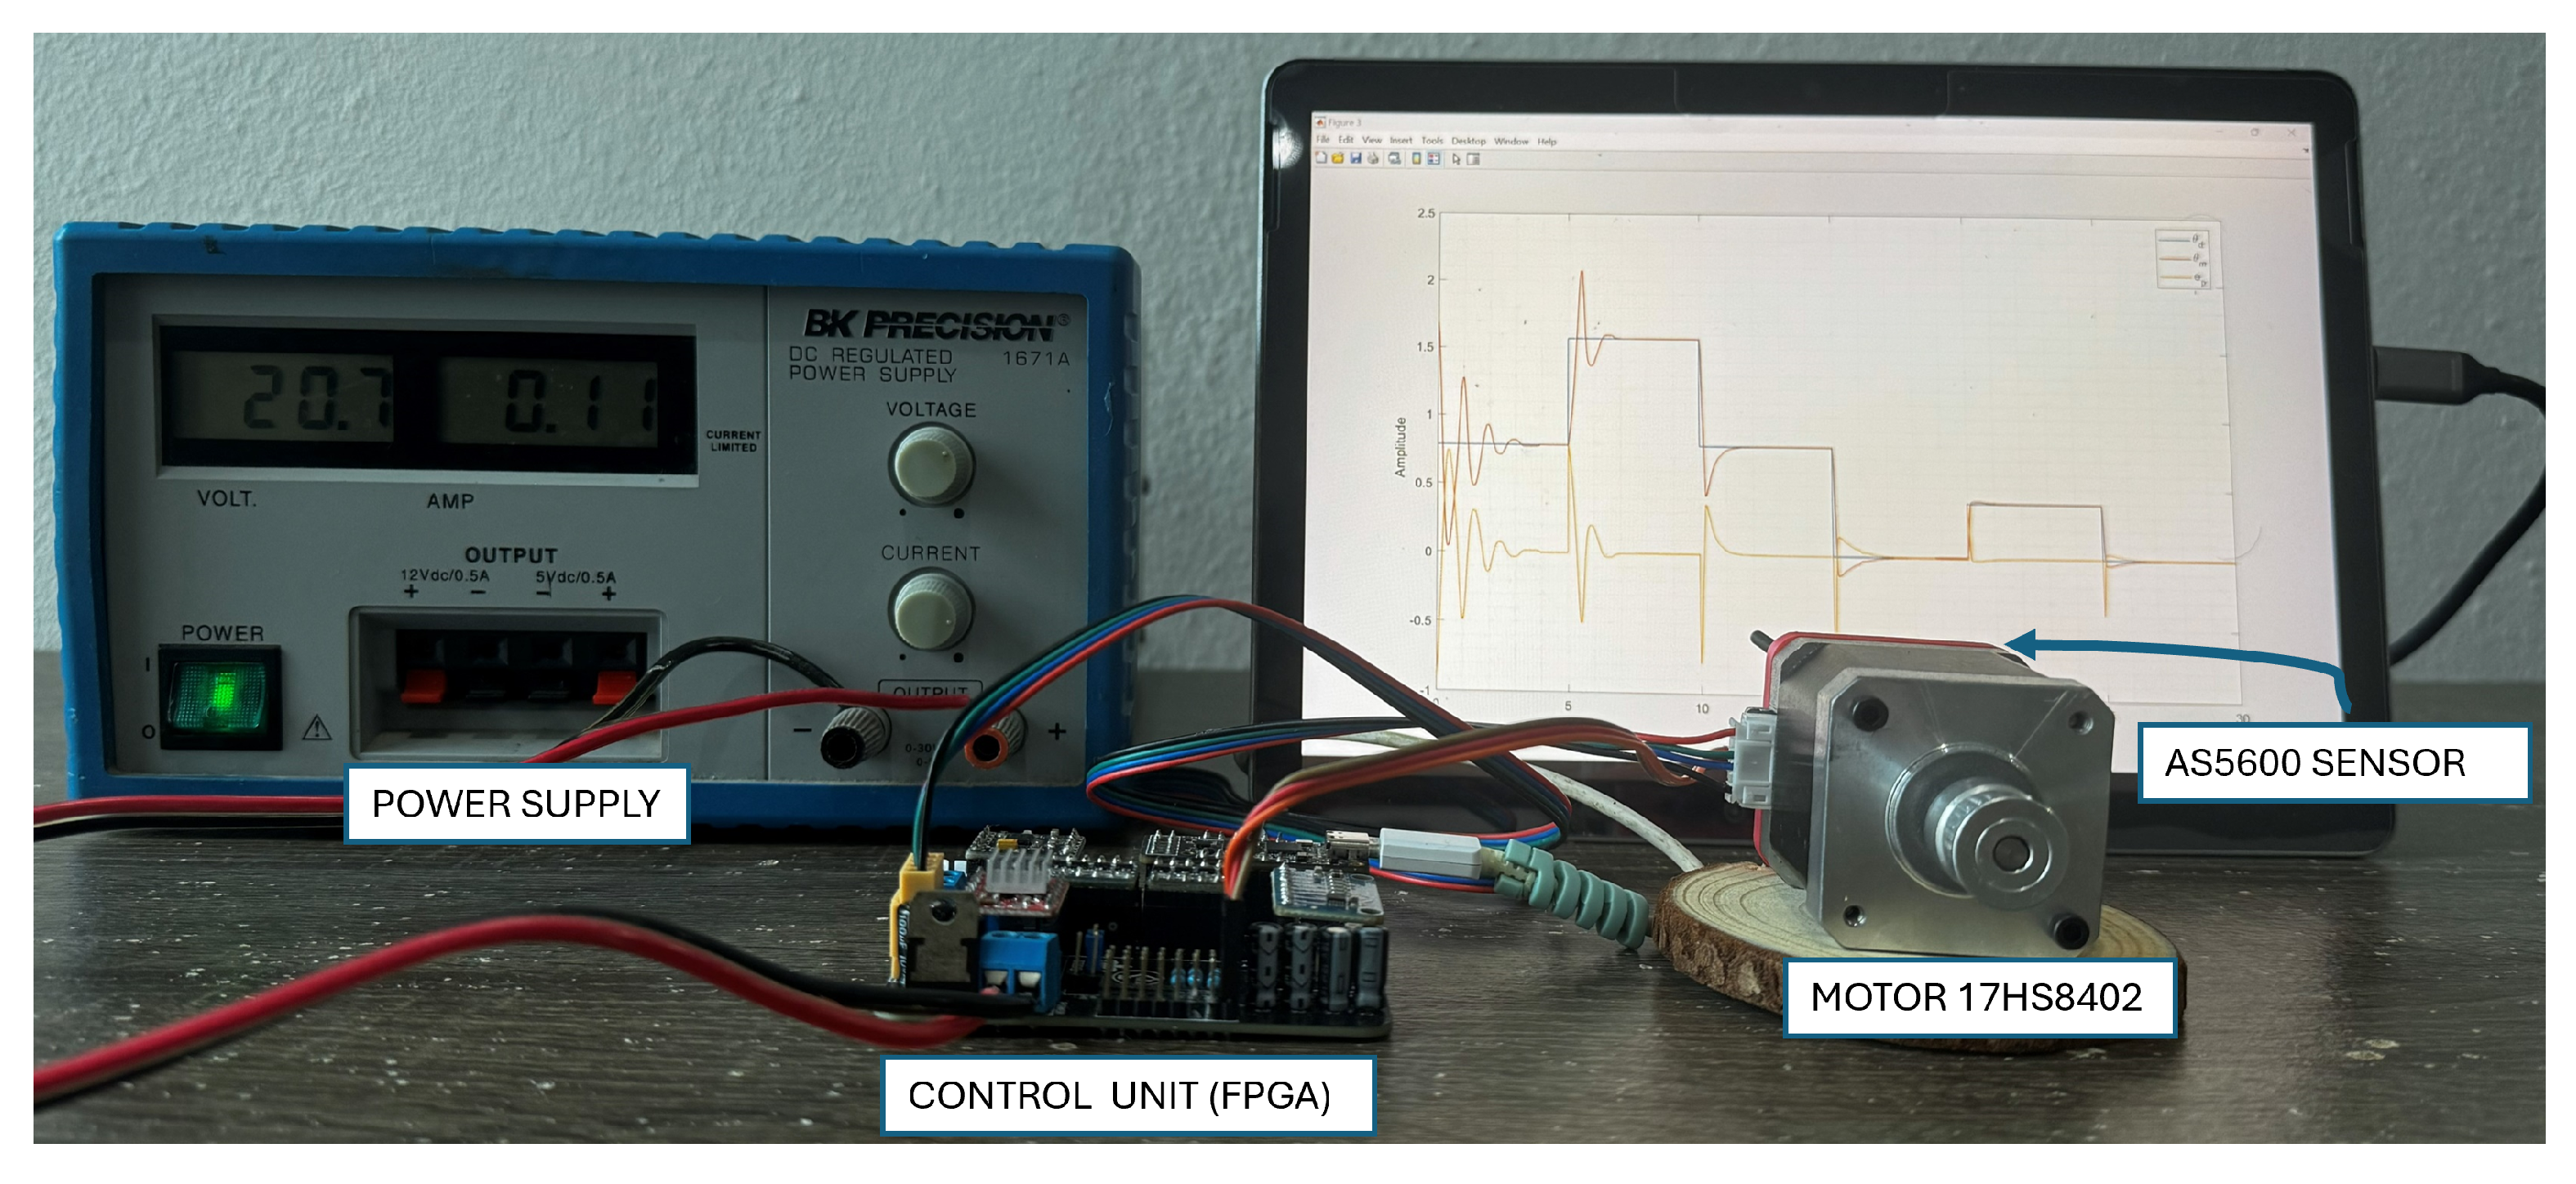
For practical application, a test bench based on a 17HS8402 motor model was used, and an AS5600 magnetic encoder OSRAM, JAPAN was employed for feedback. This encoder was configured to deliver an analog reading of 0–5 V per revolution. System response data was sent every 5 ms to MATLAB to graph its behavior. Figure 13 shows the components of the test bench.
Figure 13.
Test bench used for DC motor control.
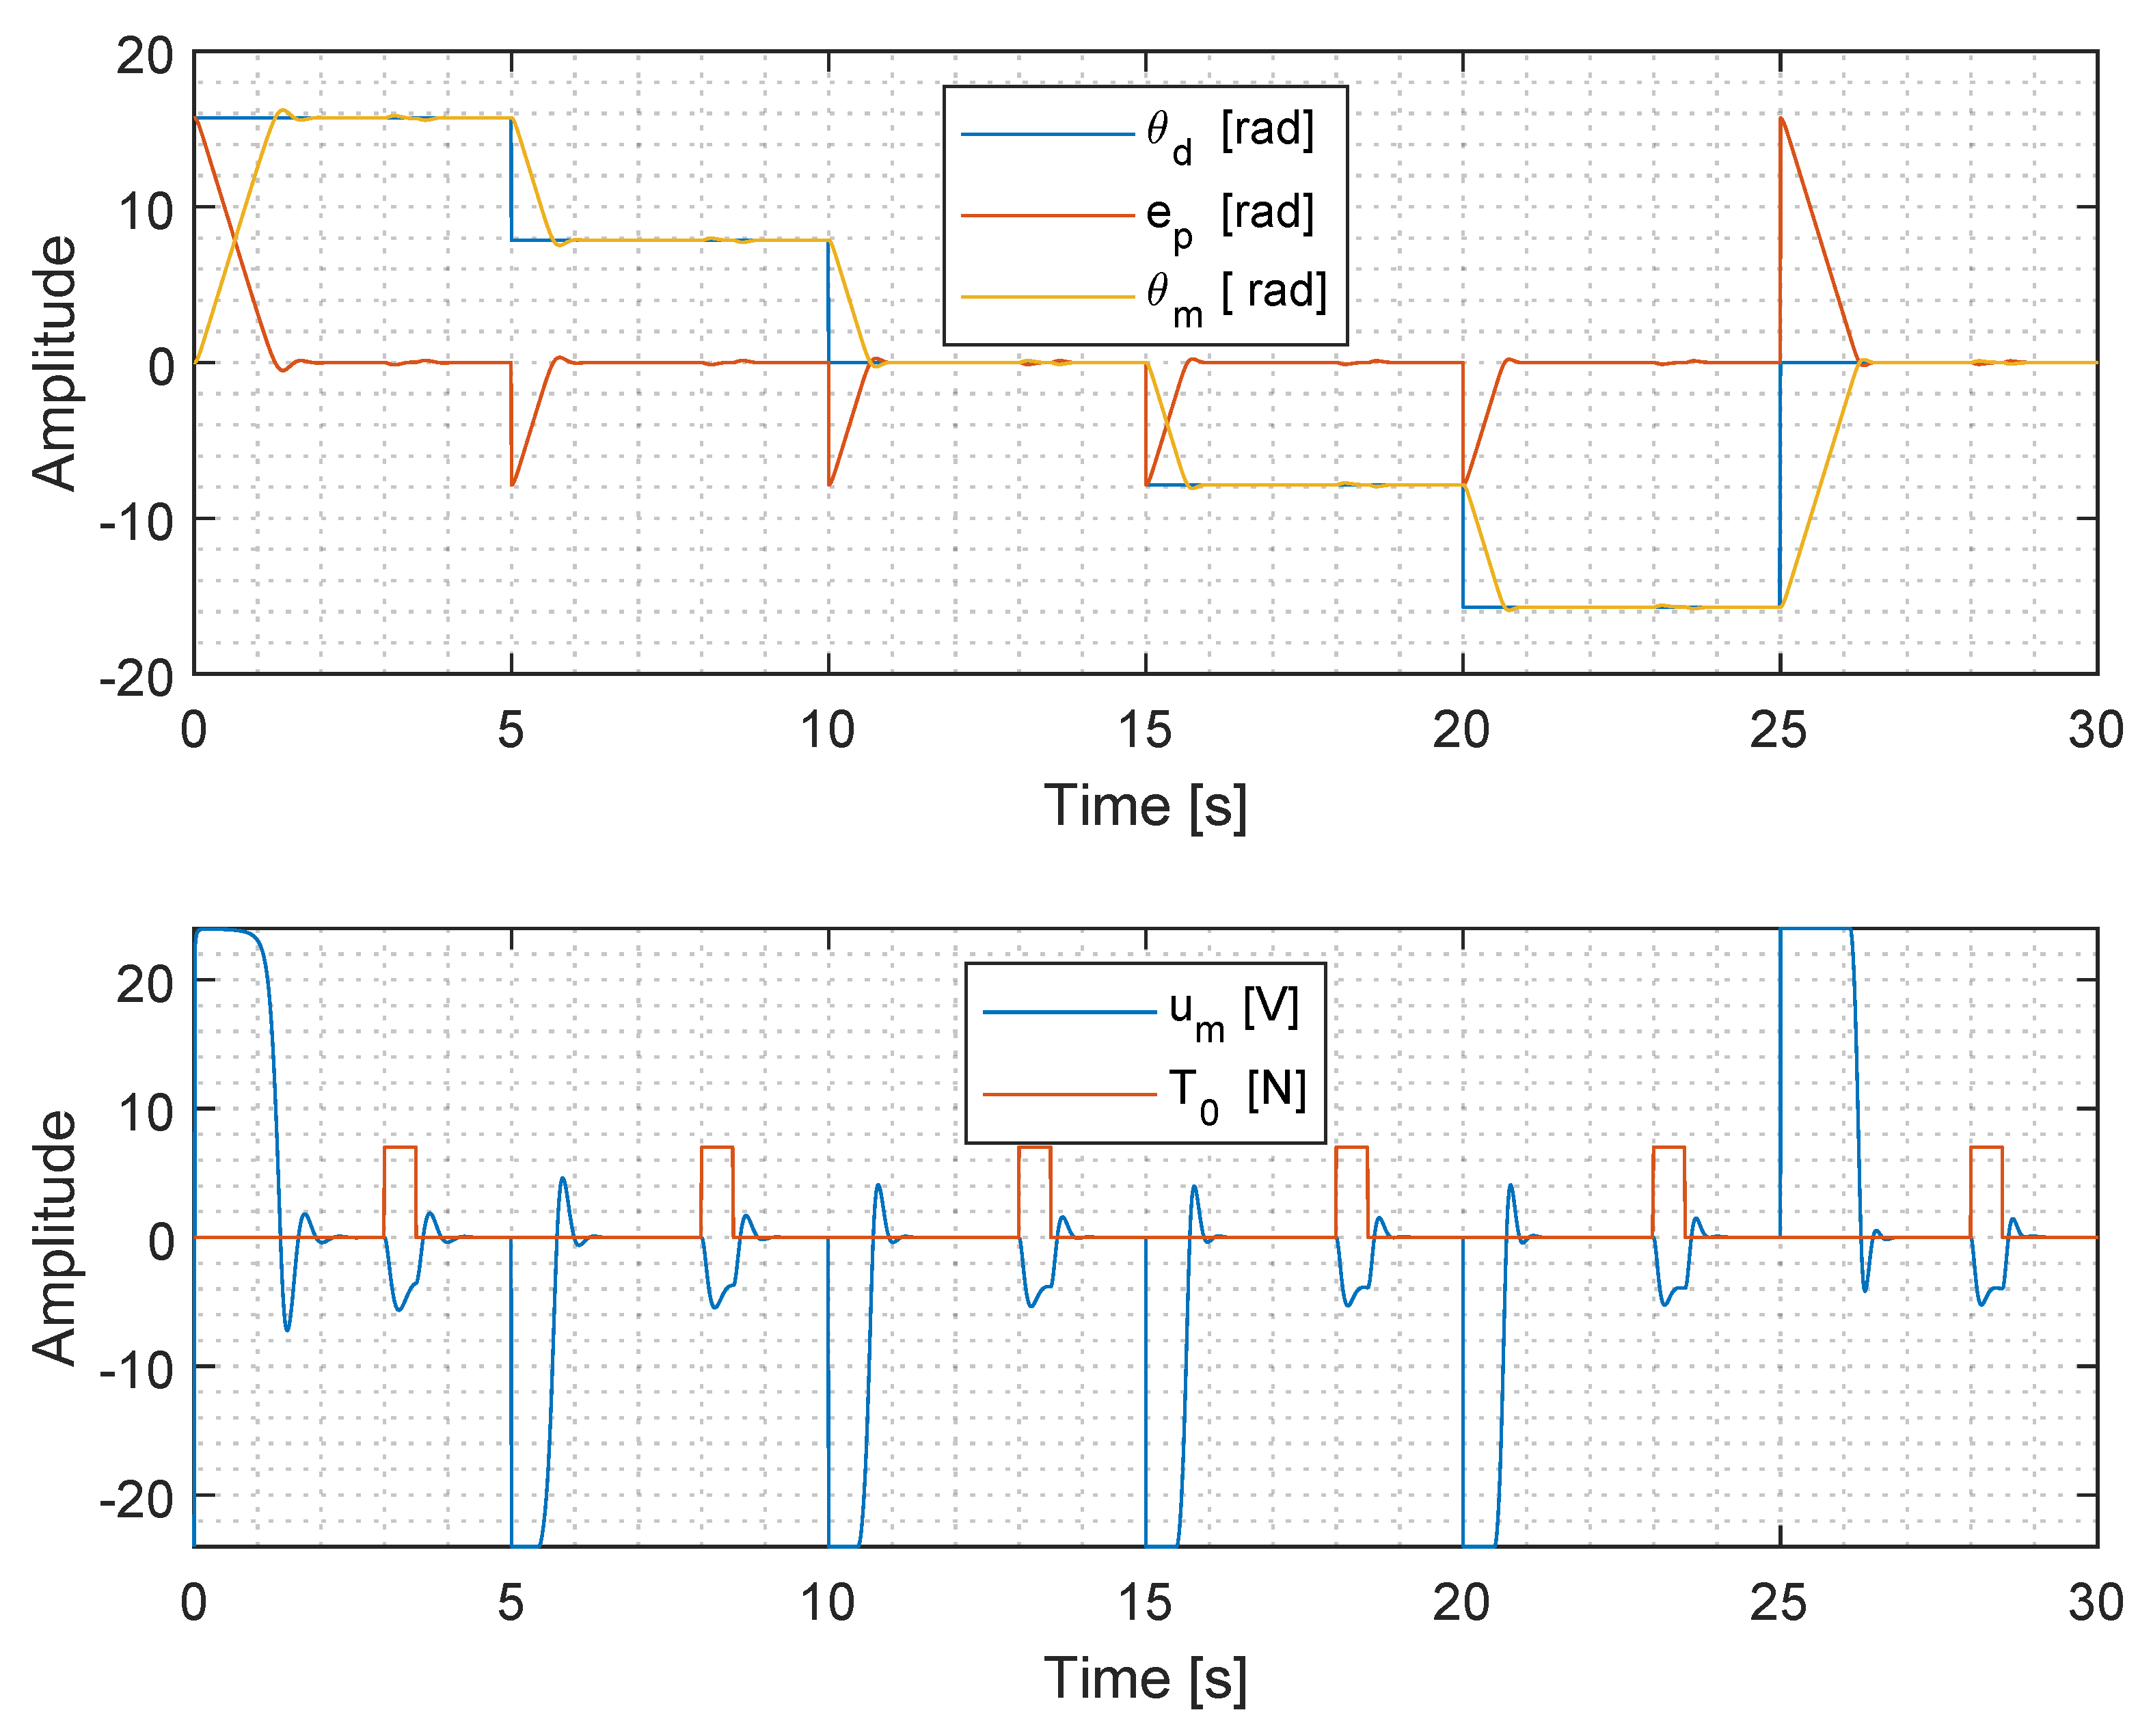
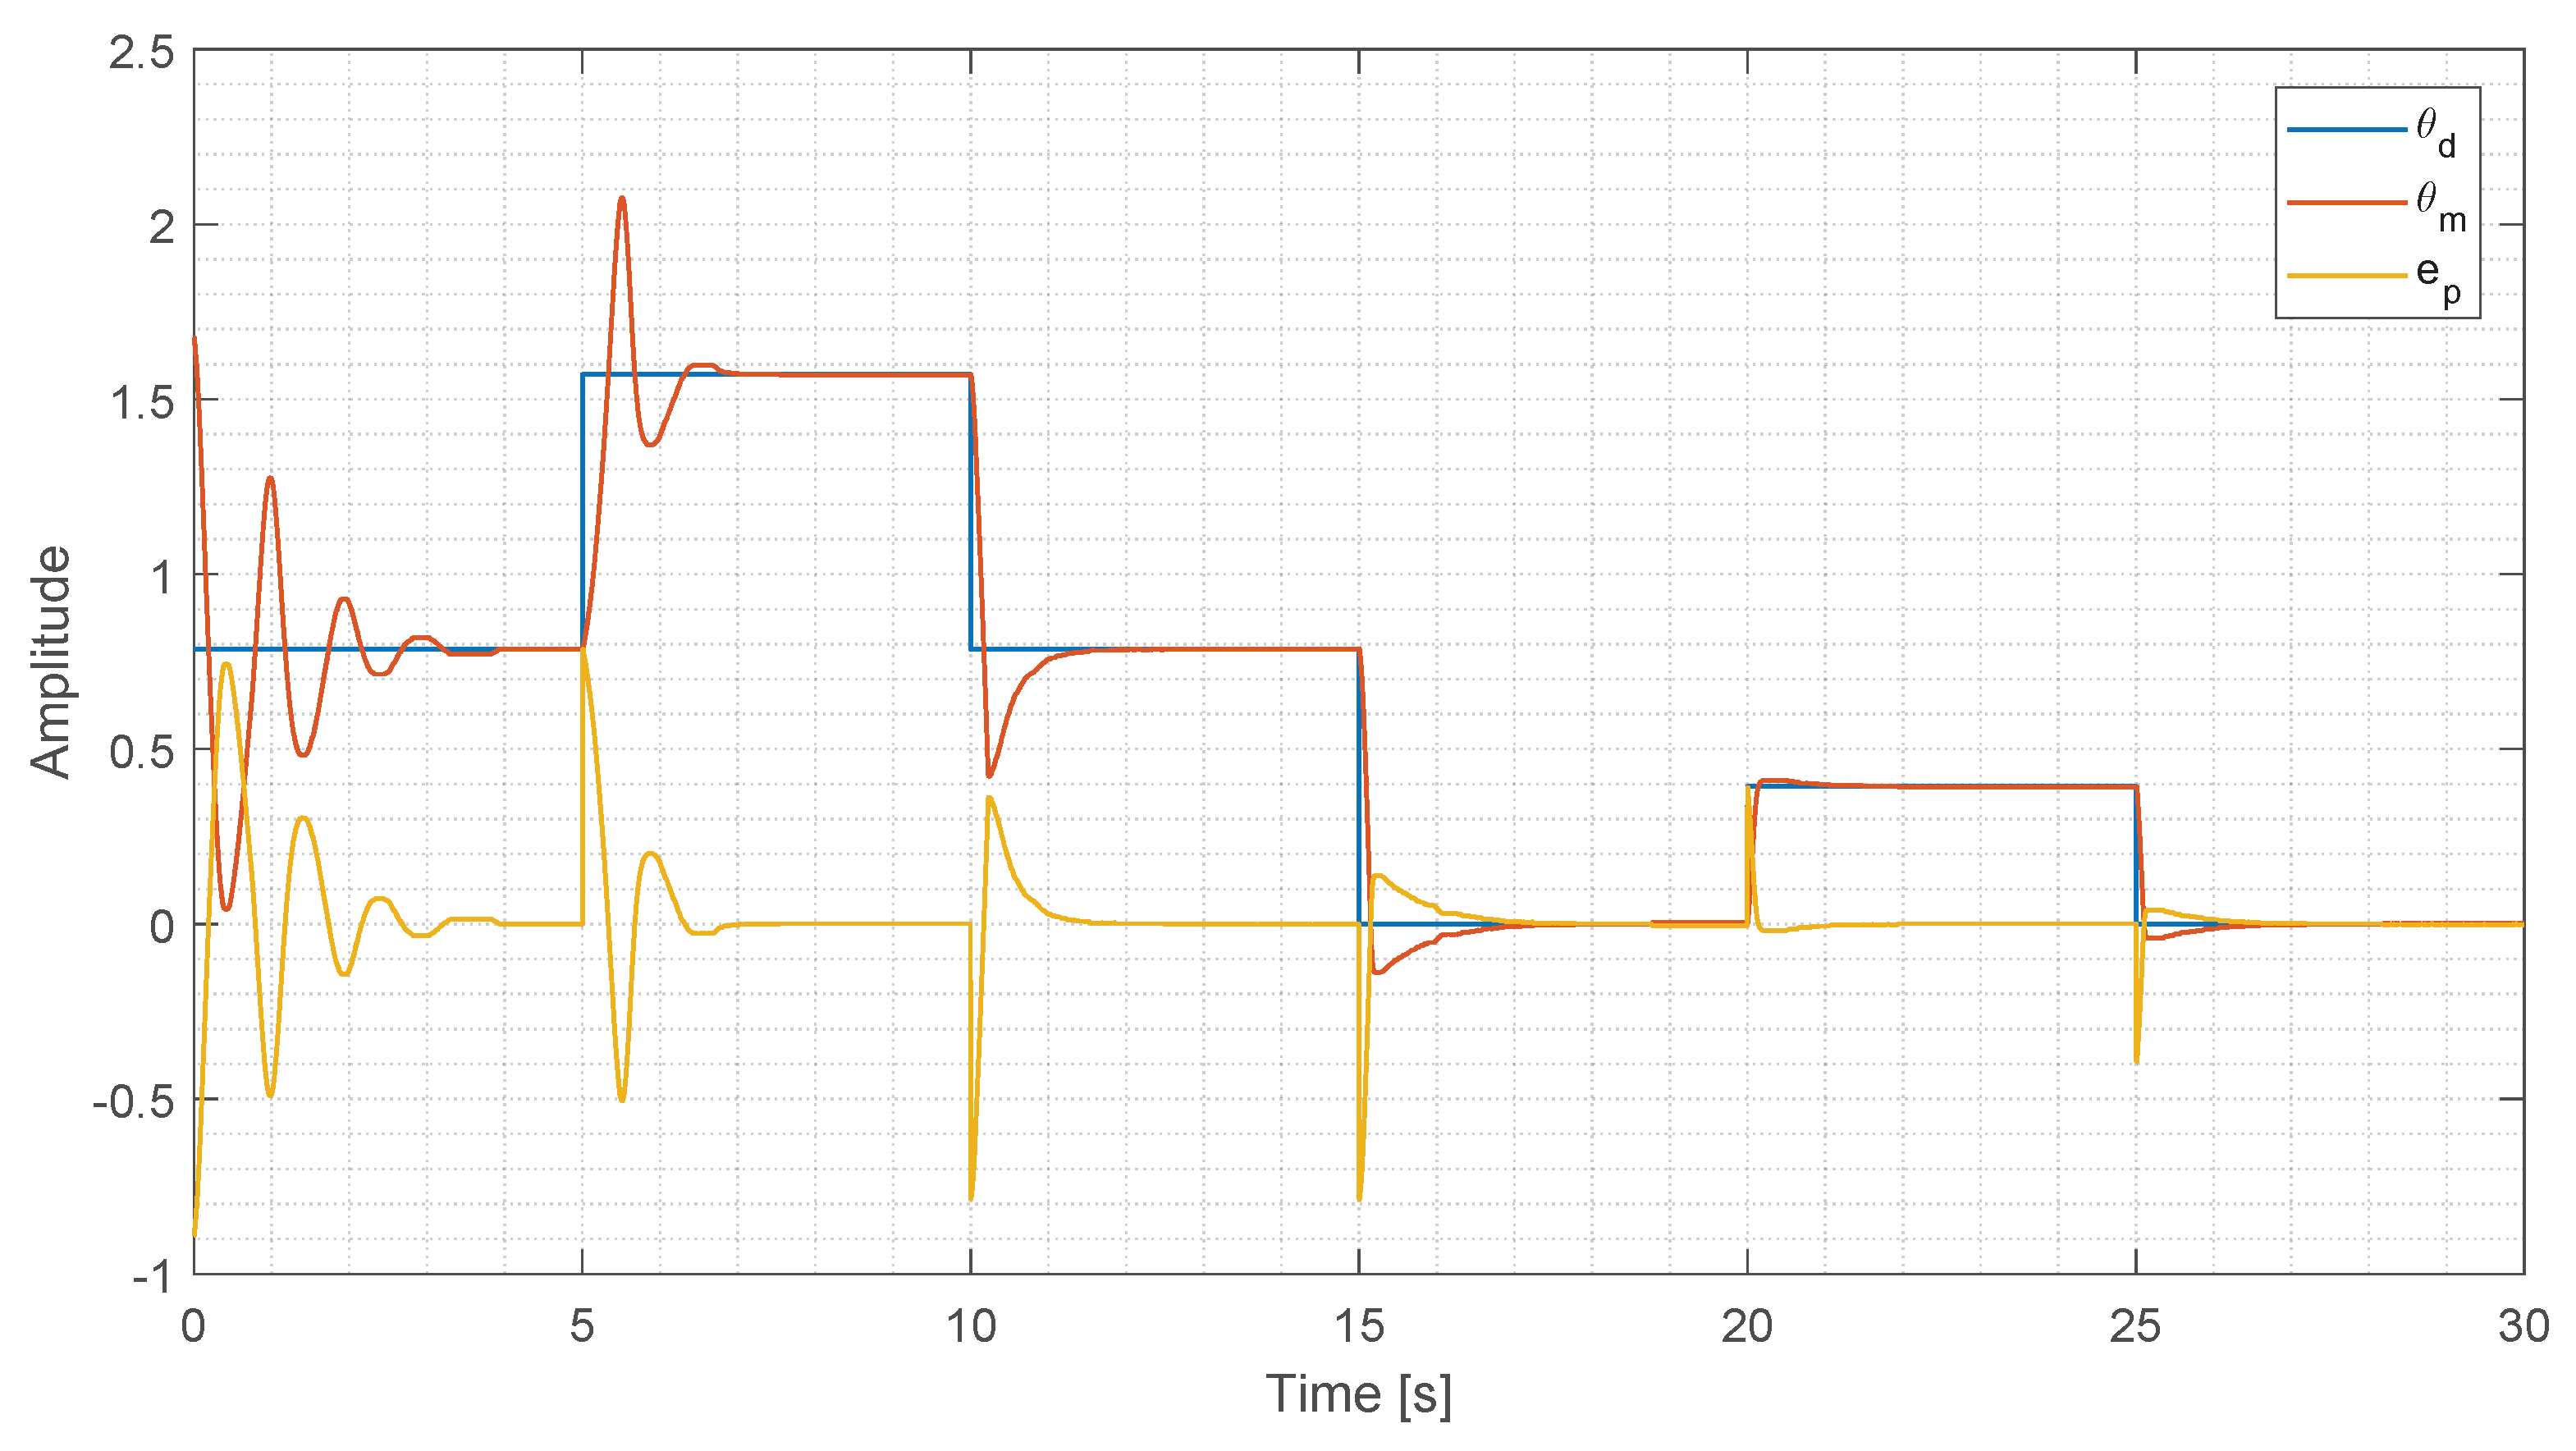
For the practical tests, six step inputs were used as a reference, with the following values: , which were changed every 5 s. A PID controller was implemented. Figure 14 shows the system’s response. The settling time is approximately 1 s, and the maximum overshoot of 32% occurs at 5 s.
Figure 14.
System response using a PID controller.
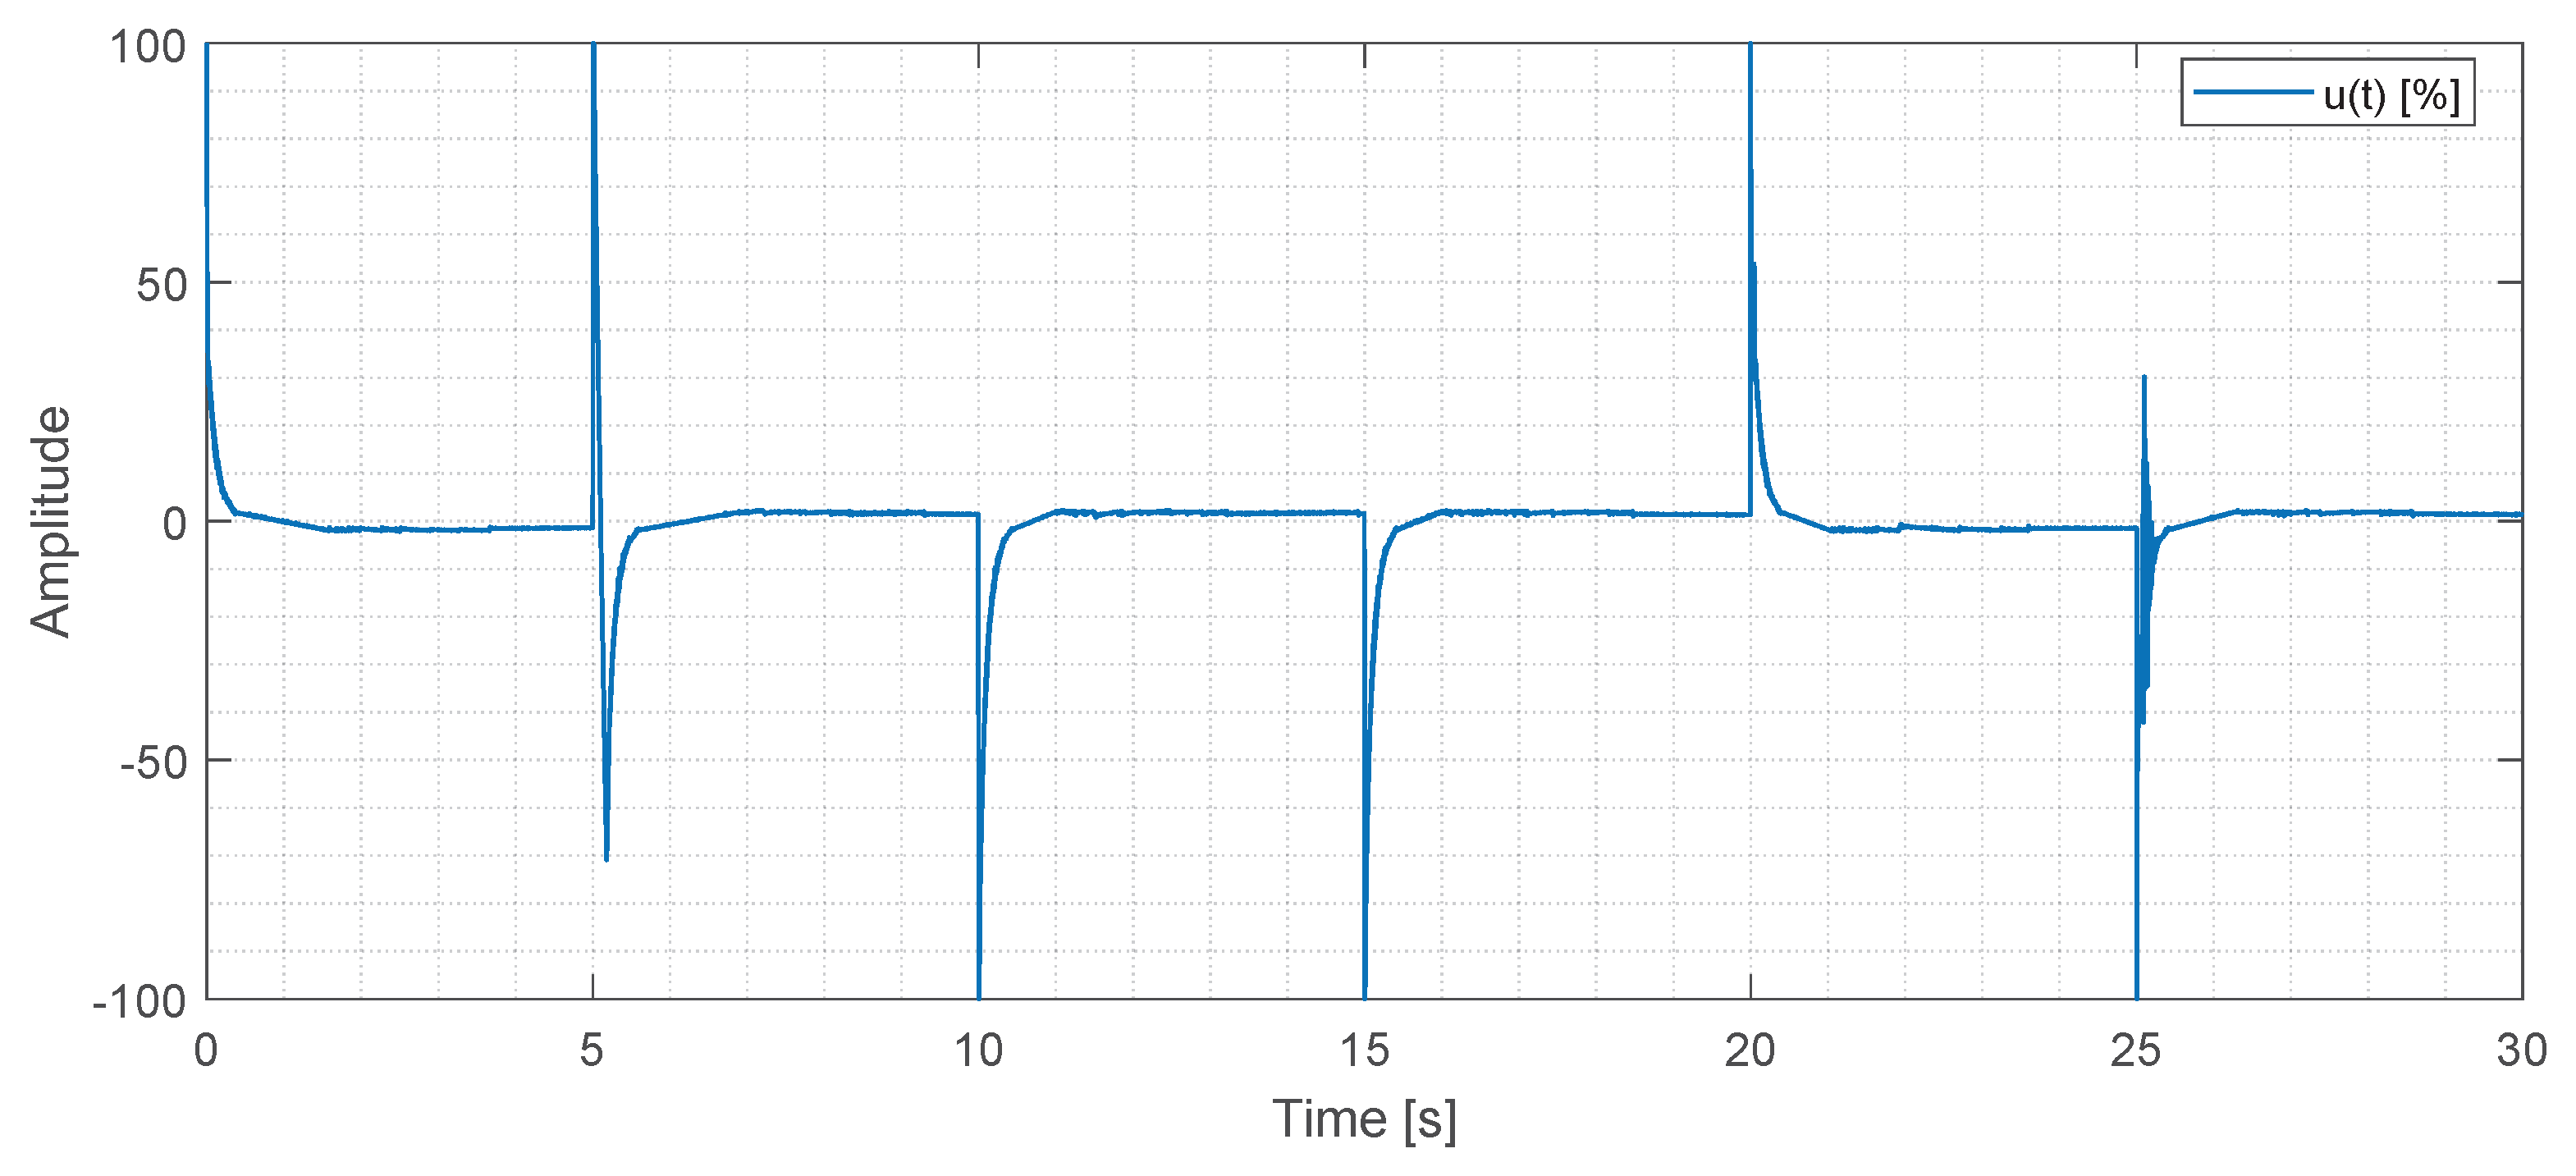
Figure 15 shows the PID control signal. As can be seen, each time a step change occurs, the PID controller uses the maximum values to force the system to reach its target.
Figure 15.
PID Control signal response.
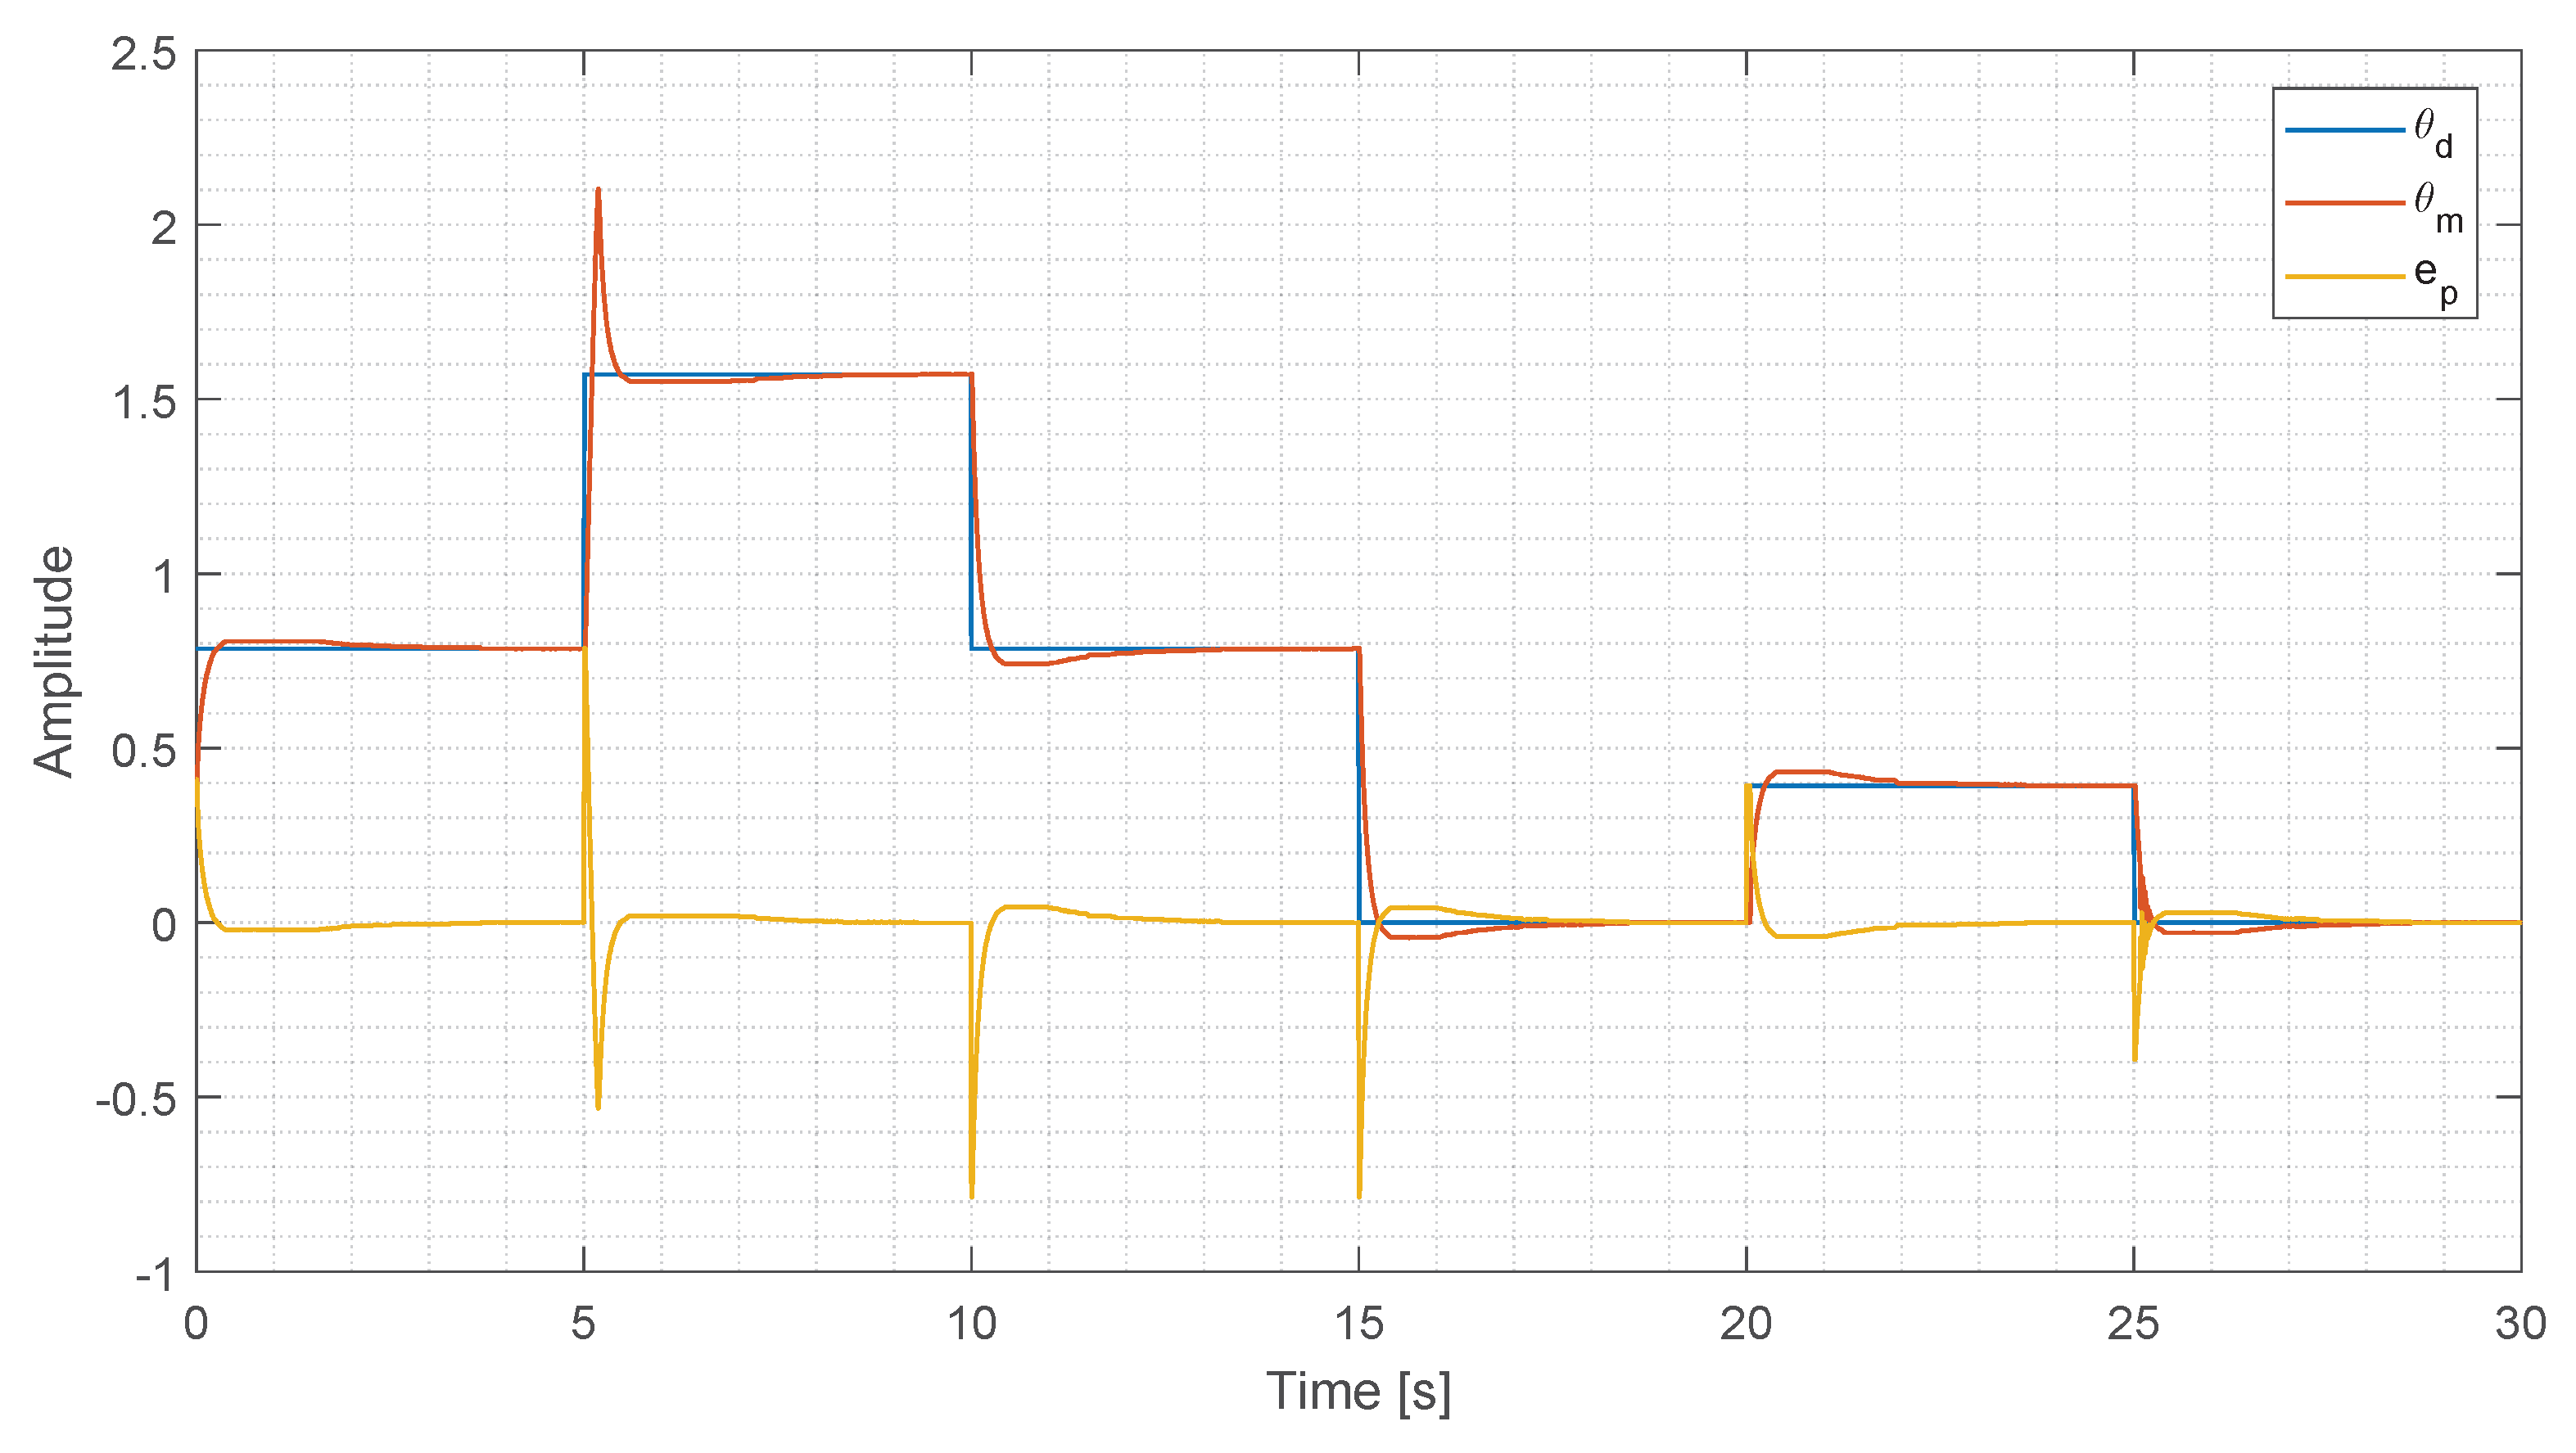
Likewise, the ANN was implemented as a controller with the characteristics described in Section 3.8.1. Figure 16 shows the system’s response when the ANN is applied as a controller. It can be observed that, during learning, the system has longer settling times (3 s and 2 s, respectively), whereas once the ANN has system information, these settling times are less than 1 s. Likewise, the maximum overshoot at 5 s is 32%, the same as the PID controller. However, these overshoots tend to decrease considerably over time.
Figure 16.
System response with the ANN.
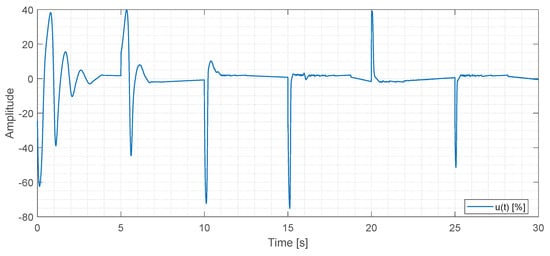
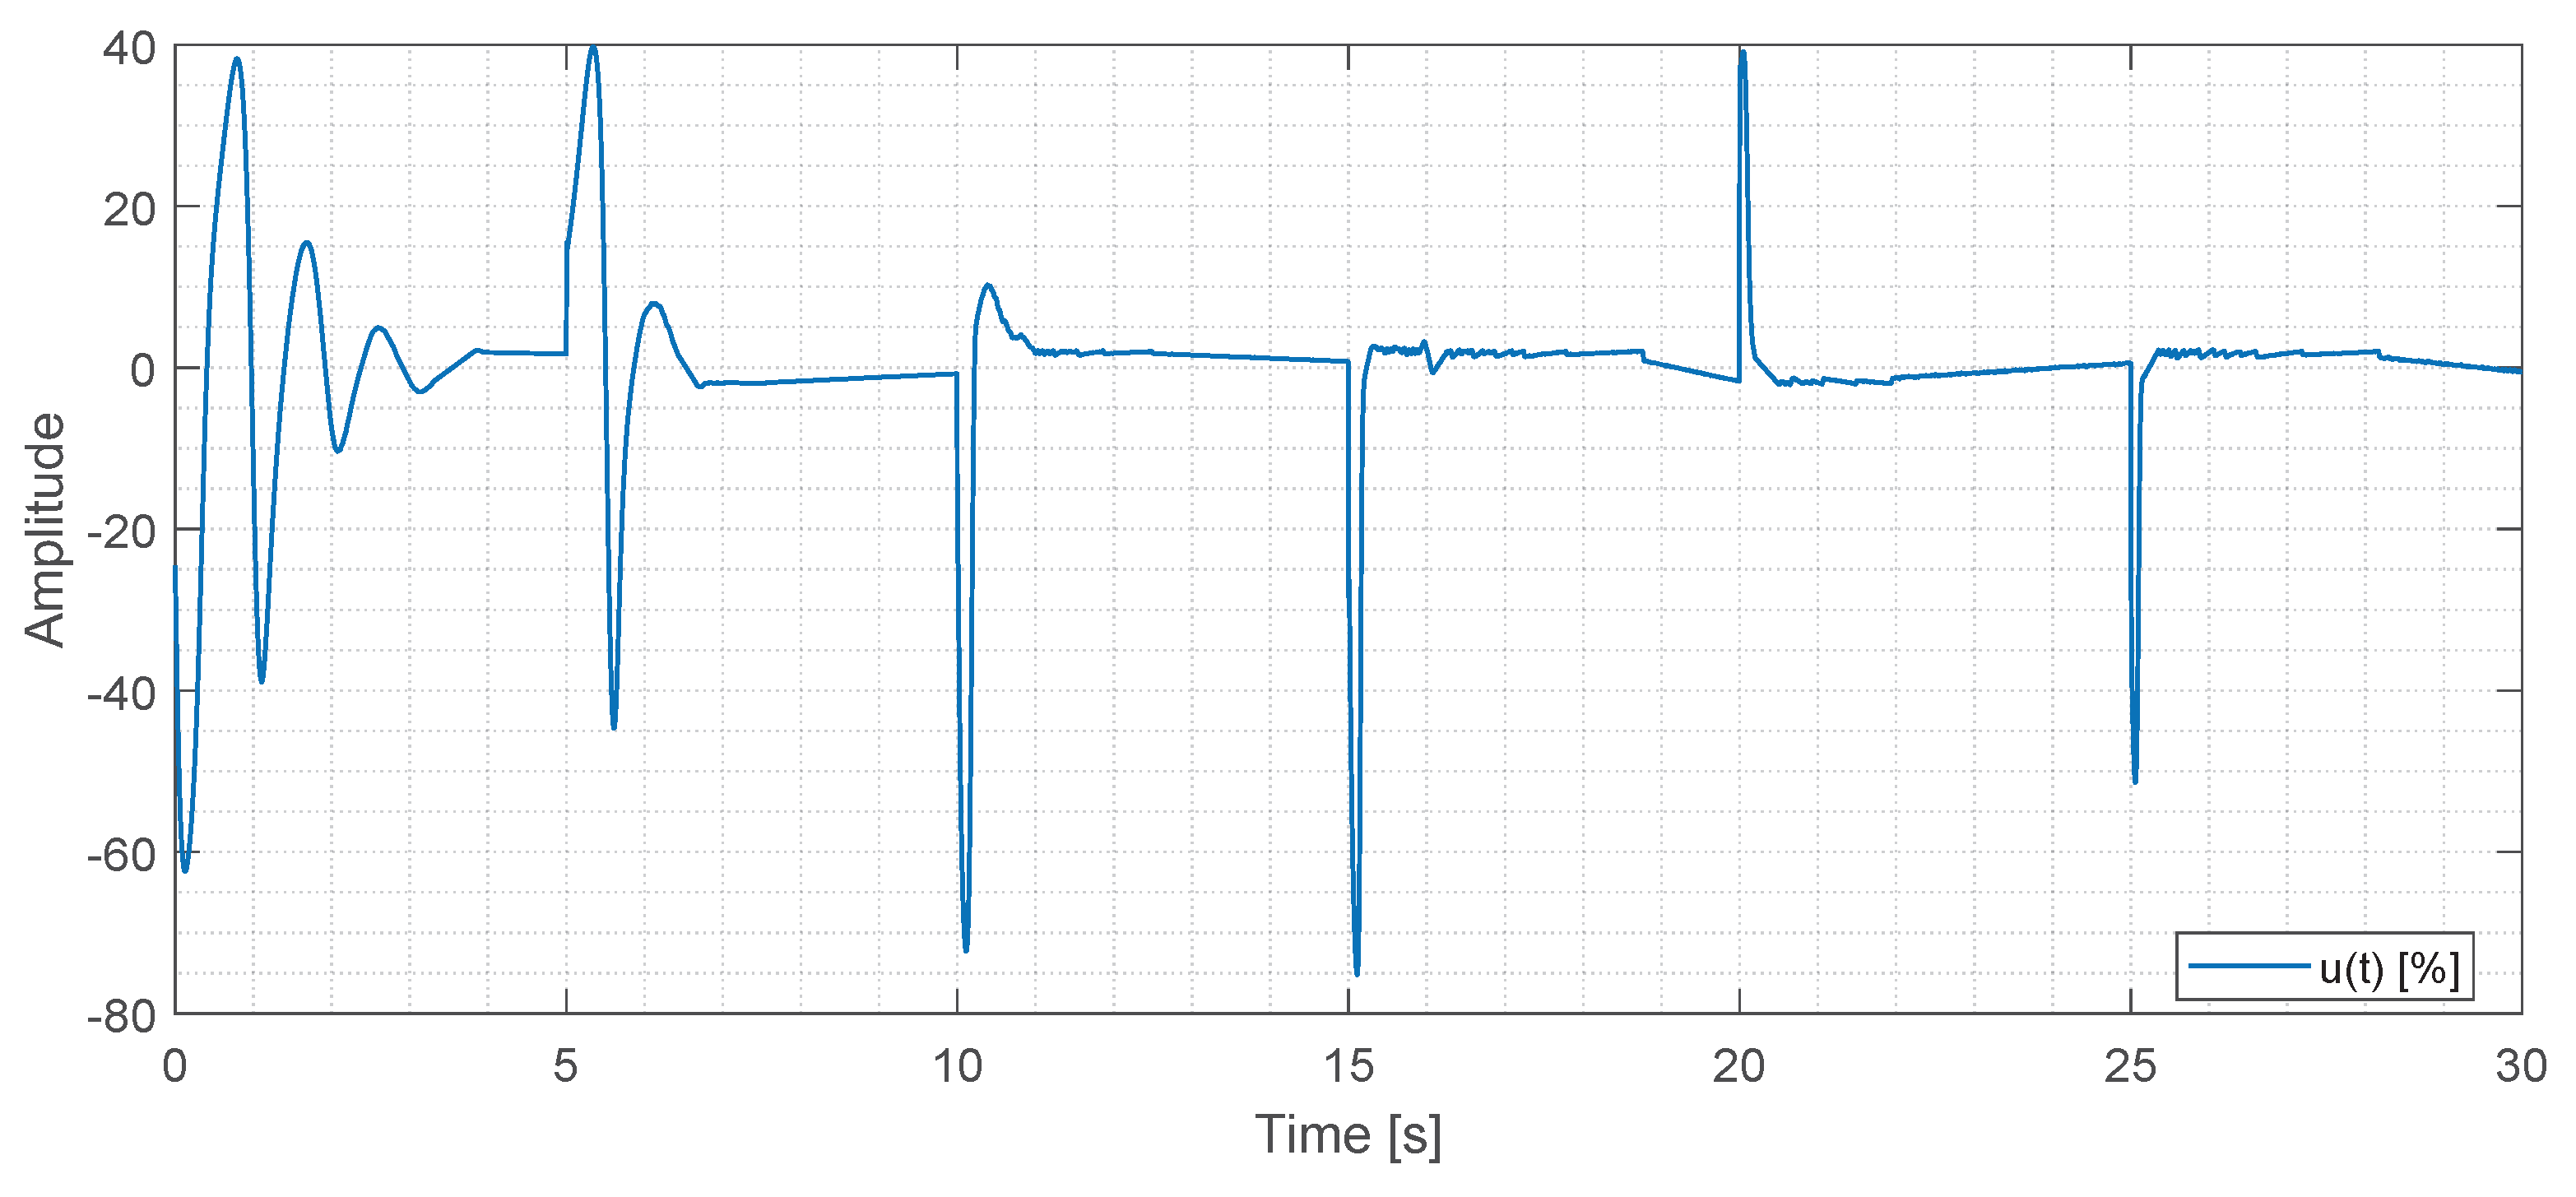
Figure 17 shows the control signal generated by the ANN. It can be observed that the amplitudes of this signal during step changes are lower (40% and 75%) than those of the PID controller.
Figure 17.
ANN control signal.
5. Discussion
Table 5 presents a detailed comparison of the logic resources employed in different works related to the use of ANNs implemented in FPGAs for the control of dynamic systems. A first notable aspect is that the proposal developed here uses significantly fewer resources, particularly in terms of DSPs, logic cells, and RAM blocks, compared to implementations reported in the literature. For example, while the proposed solution employs only 4 DSPs and 2338 logic cells, works such as [22,32] require more than 300 DSPs and tens of thousands of LUTs, reflecting the strong dependence of these architectures on high-density devices.
Another relevant element is the efficiency achieved by the proposed design considering 32-bit arithmetic precision. Despite maintaining this level of accuracy, resource consumption remains low, which contrasts with works that rely on floating-point representations, such as [22], where the reported memory cost exceeds BRAMs. Additionally, the latency measured in the proposed implementation is 16.88 ns, a competitive figure when compared to more complex adaptive architectures, such as [32], which report delays of up to 377,400 ns. From a hardware efficiency perspective, [33] presented a reconfigurable ANN architecture implemented on an Arria 10 FPGA, achieving significant area savings through adaptive reuse of hidden layers and dual-weight configurations. This demonstrates the viability of the proposed approach for real-time applications with stringent fast-response requirements.
For this case study, tests were performed using 16-bit arithmetic. While this reduces the required logic resources, quantization problems arise in systems with minimal changes, such as the IPOC system, which limits the ANN’s performance. Therefore, it was decided to present the design using 32-bit arithmetic, which provides higher resolution and thus enables the generalization of the ANN’s use as a regulator.
Regarding scalability, the results show that the design described in Figure 2 maintains constant logic resources, regardless of the number of inputs or hidden neurons used. This behavior contrasts with work based on recurrent architectures or hybrid controllers, which increase their logic resource demands exponentially with model complexity. Finally, it should be emphasized that, although the reviewed research focuses on high-end FPGAs with abundant LUTs and DSPs, the proposed methodology demonstrates that efficient neural controllers can be implemented on mid-range or low-range devices, such as the Lattice ICE40UP5K, while preserving performance and reducing computational costs.
According to the previous analysis, the results obtained show that the proposal not only maintains a competitive level compared to reference architectures but also opens new opportunities to extend the use of ANNs to the field of embedded control in devices with limited logic resources. This represents a significant step toward democratizing artificial intelligence techniques on reconfigurable hardware, demonstrating that robust performance can be achieved without relying exclusively on high-density FPGAs.
Table 5.
Comparative table of resources used by works on ANN in systems control.
6. Conclusions
In recent years, the implementation of ANN controllers on embedded platforms has faced significant challenges, particularly in terms of hardware resource consumption and computational efficiency. To address these limitations, this paper presented a self-tuning ANN regulator for dynamic systems, described using a HDL and specifically designed for implementation on low-density FPGA devices. The proposed controller incorporates an online learning mechanism based on the backpropagation algorithm, enabling continuous adaptation of neuron weight coefficients while maintaining low hardware complexity.
The proposed ANN architecture integrates several key design strategies to achieve an efficient and scalable hardware implementation. First, the use of -bit fixed-point arithmetic provides a suitable trade-off between numerical precision and resource utilization, ensuring reliable operation without the overhead associated with floating-point units. Second, the modular and parameterized design allows the ANN structure to be adjusted according to the number of inputs and hidden-layer neurons without increasing the logical resource usage. Third, the learning and inference processes are fully embedded in hardware, enabling real-time operation and deterministic latency.
To validate the proposed approach, the ANN controller was evaluated through cosimulation between ModelSim and Simulink, demonstrating a high degree of agreement between hardware and software results. Furthermore, the implementation was deployed on three low- to mid-range FPGA devices, and resource utilization was carefully analyzed. The experimental results show that the architecture consumes approximately 50% of the available DSP units, around 30% of logic cells, and only 6% of embedded memory blocks, confirming its suitability for resource-constrained platforms.
The performance of the proposed ANN regulator was assessed using three dynamic systems with distinct characteristics. For a linear and stable system, the ANN controller achieved an overshoot of less than 10% and settling times below 1 s under step reference changes. For a nonlinear system, the maximum overshoot was limited to 20%, with settling times under 2 ms. For both systems, a compact ANN configuration with three inputs, three hidden neurons, and one output was sufficient, requiring only 292 clock cycles. For a third system characterized by nonlinear and unstable dynamics, a larger network with six inputs and ten hidden neurons was implemented, requiring 1432 clock cycles while maintaining stable and accurate regulation.
Additionally, the impact of sampling time and computational latency was thoroughly analyzed. The sampling periods for the evaluated systems were selected based on their dynamic behavior and on the ANN computation time, which scales as clock cycles. Using a 50 MHz clock, the control signal computation required approximately 6 μs for the motor and Buck converter systems, and 29 μs for the IPOC system. Although increasing the number of inputs or hidden neurons increases computational latency, experimental tests with up to 64 hidden neurons showed that acceptable performance can be achieved without modifying the operating frequency. Moreover, the results confirm that, for typical control applications, a relatively small number of hidden neurons is sufficient.
In the practical validation stage, a direct comparison with a conventional PID controller revealed that the PID produces control signals with significantly higher magnitude during position changes. In contrast, the ANN-based controller generates smoother control actions. Furthermore, as the ANN progressively learns the system dynamics, the overshoot in the system response is noticeably reduced. Importantly, unlike the PID controller, which requires prior knowledge and tuning based on plant parameters, the proposed ANN controller could regulate the motor position without explicit understanding of the system parameters.
Unlike most existing ANN-based control implementations that rely on high-density FPGAs with abundant hardware resources, the proposed design maintains constant logical resource usage regardless of the network size. This characteristic highlights the potential of low- and medium-density FPGA devices as practical and efficient platforms for neural-network-based control applications.
Although this work focuses on ANN controllers for dynamic systems, the proposed architecture and design methodology are extendable. The modular hardware structure, fixed-point learning mechanism, and deterministic latency analysis can be applied to other intelligent control strategies and embedded learning systems. Future work will focus on further optimizing the learning algorithm to reduce computational latency and on exploring the implementation of more advanced neural architectures and their application to high-speed and multi-variable control systems.
Author Contributions
Conceptualization, E.E.C.-M. and J.R.G.-M.; methodology, E.E.C.-M., J.R.G.-M., J.R.-R., J.O.-S., J.M.Á.-A. and O.A.B.-V.; software, E.E.C.-M.; validation, E.E.C.-M., J.R.G.-M., J.R.-R., J.O.-S., J.M.Á.-A. and O.A.B.-V.; formal analysis, J.R.-R. and J.O.-S.; investigation, E.E.C.-M., J.R.G.-M., J.R.-R., J.O.-S., J.M.Á.-A. and O.A.B.-V.; resources, J.R.G.-M. and O.A.B.-V.; data curation, E.E.C.-M. and J.R.G.-M.; writing—original draft preparation, E.E.C.-M., J.R.G.-M., J.R.-R., J.O.-S., J.M.Á.-A. and O.A.B.-V.; writing—review and editing, E.E.C.-M., J.R.G.-M., J.R.-R., J.O.-S., J.M.Á.-A. and O.A.B.-V.; visualization, J.R.-R., J.O.-S. and J.M.Á.-A.; supervision, J.R.-R. and J.O.-S.; project administration, E.E.C.-M. and J.R.G.-M.; funding acquisition, E.E.C.-M., J.R.G.-M., J.R.-R., J.O.-S., J.M.Á.-A. and O.A.B.-V. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Data Availability Statement
The original contributions presented in this study are included in the article. Further inquiries can be directed to the corresponding author.
Acknowledgments
The first author thanks the “Facultad de Ingeniería en Electrónica y Comunicaciones, Universidad Veracruzana, Región: Poza Rica—Tuxpan” for its support of this research and the “Secretaría de Ciencia, Humanidades, Tecnología e Innovación” (SECIHTI). Grammarly was used to check grammar in this manuscript.
Conflicts of Interest
The authors declare no conflict of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| FPGA | Field-Programmable Gate Array |
| HDL | Hardware Description Language |
| ANN | Artificial Neuronal Network |
| RNN | Recurrent Neuronal Network |
| AONPC | Adaptive Online Neural Predictive Controller |
| IPOC | Inverted Pendulum On Cart |
| DC | Direct Current |
| DSP | Digital Signal Processor |
| PID | Proportional-Integral-Derivative |
| RAM | Random Access Memory |
| MAC | Multiply–Accumulate |
References
- Vinnakoti, S.; Kota, V.R. Implementation of artificial neural network based controller for a five-level converter based UPQC. Alex. Eng. J. 2018, 57, 1475–1488. [Google Scholar] [CrossRef] [Scilit]
- Saady, M.M.; Essai, M.H. Hardware implementation of neural network-based engine model using FPGA. Alex. Eng. J. 2022, 61, 12039–12050. [Google Scholar] [CrossRef] [Scilit]
- Zhu, B.; Karimi, H.R.; Zhang, L.; Zhao, X. Neural network-based adaptive reinforcement learning for optimized backstepping tracking control of nonlinear systems with input delay. Appl. Intell. 2025, 55, 129. [Google Scholar] [CrossRef] [Scilit]
- Liu, J.; Wu, J.; Pan, J.; Zhao, P. Fuzzification-back propagation neural network-based model prediction for robotic arm positioning error reduction. Eng. Appl. Artif. Intell. 2025, 151, 110639. [Google Scholar] [CrossRef] [Scilit]
- Chen, Y.P.; Karkaria, V.; Tsai, Y.K.; Rolark, F.; Quispe, D.; Gao, R.X.; Cao, J.; Chen, W. Real-time decision-making for Digital Twin in additive manufacturing with Model Predictive Control using time-series deep neural networks. J. Manuf. Syst. 2025, 80, 412–424. [Google Scholar] [CrossRef] [Scilit]
- Gallon, R.; Schiemenz, F.; Menicucci, A.; Gill, E. Convolutional neural network design and evaluation for real-time multivariate time series fault detection in spacecraft attitude sensors. Adv. Space Res. 2025, 76, 2960–2976. [Google Scholar] [CrossRef] [Scilit]
- El Bouazzaoui, A.; Mouhib, O.; Hadjoudja, A. NeuroAdaptiveNet: A Reconfigurable FPGA-Based Neural Network System with Dynamic Model Selection. Chips 2025, 4, 24. [Google Scholar] [CrossRef] [Scilit]
- Muller, J.M.; Brisebarre, N.; De Dinechin, F.; Jeannerod, C.P.; Lefevre, V.; Melquiond, G.; Revol, N.; Stehlé, D.; Torres, S. Handbook of Floating-Point Arithmetic; Springer: Basel, Switzerland, 2018; Volume 1. [Google Scholar]
- Jung, S.; Kim, S.S. Hardware implementation of a real-time neural network controller with a DSP and an FPGA for nonlinear systems. IEEE Trans. Ind. Electron. 2007, 54, 265–271. [Google Scholar] [CrossRef] [Scilit]
- Purkayastha, A.A.; Tharwani, J.; Aggarwal, S. FPGA or GPU? Analyzing Comparative Research for Application-Specific Guidance. In Proceedings of the SoutheastCon 2025, Concord, NC, USA, 22–30 March 2025; pp. 1258–1263. [Google Scholar]
- Farooq, U.; Marrakchi, Z.; Mehrez, H. FPGA architectures: An overview. In Tree-Based Heterogeneous FPGA Architectures: Application Specific Exploration and Optimization; Springer: New York, NY, USA, 2012; pp. 7–48. [Google Scholar]
- Roberts, T.; Satme, J.N.; Chowdhury, P.; Downey, A.R.; Bakos, J.D. Resource-efficient FPGA-based machine learning control for active structural damping in shock environments. In Proceedings of the Active and Passive Smart Structures and Integrated Systems XIX; SPIE: Vancouver, BC, Canada, 2025; Volume 13432, pp. 66–78. [Google Scholar]
- Dinelli, G.; Meoni, G.; Rapuano, E.; Fanucci, L. Advantages and limitations of fully on-chip CNN FPGA-based hardware accelerator. In Proceedings of the 2020 IEEE International Symposium on Circuits and Systems (ISCAS), Seville, Spain, 12–14 October 2020; pp. 1–5. [Google Scholar]
- Greco, L.; Moscato, F.; Ritrovato, P.; Vento, M. Fast and low cost FPGA-based architecture for arrhythmia detection with CNN. Internet Things 2025, 33, 101705. [Google Scholar] [CrossRef] [Scilit]
- Saeed, A.B.; Gitaffa, S.A.; Dawai, R.I. FPGA-Based Realization of Intelligent Escalator Controller Using Artificial Neural Network. J. Electr. Comput. Eng. 2025, 2025, 7567924. [Google Scholar] [CrossRef] [Scilit]
- Kakodia, S.K.; Dyanamina, G. Implementation of FPGA-based Neural Network Controller for Reducing Speed Ripple for a PMSM-driven EV using MRAS Speed Estimator. IEEE Trans. Artif. Intell. 2025. [Google Scholar] [CrossRef] [Scilit]
- Fekik, A.; Khati, H.; Azar, A.T.; Hamida, M.L.; Denoun, H.; Kamal, N.A. FPGA-based performance evaluation of backstepping control and computed torque control for industrial robots. Int. J. Autom. Control 2025, 19, 101–132. [Google Scholar] [CrossRef] [Scilit]
- Khaki, A.M.Z.; Choi, A. Real-time and Resource-efficient Embedded Computer Vision Via Optimizing Lightweight CNNs for FPGA Acceleration. J. Signal Process. Syst. 2025, 97, 185–195. [Google Scholar] [CrossRef] [Scilit]
- Cabrera-Rufino, M.A.; Ramos-Arreguín, J.M.; Rodríguez-Reséndiz, J.; Gorrostieta-Hurtado, E.; Aceves-Fernandez, M.A. Implementation of ANN-based auto-adjustable for a pneumatic servo system embedded on FPGA. Micromachines 2022, 13, 890. [Google Scholar] [CrossRef] [Scilit]
- Shively, S.; Jackson, N.; Chabot, E.; DiCecco, J.; Koziol, S. Data Sampling System for Processing Event Camera Data Using a Stochastic Neural Network on an FPGA. Electronics 2025, 14, 3094. [Google Scholar] [CrossRef] [Scilit]
- Singh, S.; Kishore, K.; Akbar, S. Neuro-evolutionary based controller design for linear and non-linear systems. In Proceedings of the 2021 21st International Conference on Control, Automation and Systems (ICCAS), Jeju, Republic of Korea, 12–15 October 2021; pp. 211–215. [Google Scholar]
- Hingu, C.; Fu, X.; Vangala, P.; Mishan, R.; Fajri, P. 32-Bit Fixed and Floating-Point Hardware Implementation for Enhanced Inverter Control: Leveraging FPGA in Recurrent Neural Network Applications. IEEE Access 2024, 12, 111097–111110. [Google Scholar] [CrossRef] [Scilit]
- Han, J.; Li, Z.; Zheng, W.; Zhang, Y. Hardware implementation of spiking neural networks on FPGA. Tsinghua Sci. Technol. 2020, 25, 479–486. [Google Scholar] [CrossRef] [Scilit]
- Zhang, L.; Krestinskaya, O.; Fouda, M.E.; Eltawil, A.M.; Salama, K.N. Quantized convolutional neural networks: A hardware perspective. Front. Electron. 2025, 6, 1469802. [Google Scholar] [CrossRef] [Scilit]
- Pistellato, M.; Bergamasco, F.; Bigaglia, G.; Gasparetto, A.; Albarelli, A.; Boschetti, M.; Passerone, R. Quantization-aware nn layers with high-throughput fpga implementation for edge ai. Sensors 2023, 23, 4667. [Google Scholar] [CrossRef] [Scilit]
- Yu, F.; Kong, X.; Yao, W.; Zhang, J.; Cai, S.; Lin, H.; Jin, J. Dynamics analysis, synchronization and FPGA implementation of multiscroll Hopfield neural networks with non-polynomial memristor. Chaos Solitons Fractals 2024, 179, 114440. [Google Scholar] [CrossRef] [Scilit]
- Silva-Ortigoza, R.; Hernández-Márquez, E.; Roldán-Caballero, A.; Tavera-Mosqueda, S.; Marciano-Melchor, M.; García-Sánchez, J.R.; Hernández-Guzmán, V.M.; Silva-Ortigoza, G. Sensorless tracking control for a “full-bridge Buck inverter–DC motor” system: Passivity and flatness-based design. IEEE Access 2021, 9, 132191–132204. [Google Scholar] [CrossRef] [Scilit]
- García-Chávez, R.E.; Silva-Ortigoza, R.; Hernández-guzmáN, V.M.; Marciano-Melchor, M.; Orta-Quintana, Á.A.; García-Sánchez, J.R.; Taud, H. A robust sliding mode and PI-based tracking control for the MIMO “DC/DC buck converter–inverter–DC motor” system. IEEE Access 2023, 11, 119396–119408. [Google Scholar] [CrossRef] [Scilit]
- Fu, W.; Li, J.; Zhang, Y.; Du, W.; Chen, X. Design and Performance Analysis of a Non-Isolated DC-DC Converter With a Fractional-Order Output Filtering Capacitor. IEEE Trans. Circuits Syst. II Express Briefs 2024, 71, 4336–4340. [Google Scholar] [CrossRef] [Scilit]
- Siddiqui, M.A.; Akhtar, S.A.; Akhtar, S.F.; Fatima, F. Control of Cart Inverted Pendulum System Using Model Matching in Cascade Control Architecture. In Proceedings of the 2024 IEEE 11th International Conference on E-Learning in Industrial Electronics (ICELIE), Chicago, IL, USA, 3–6 November 2024; pp. 1–6. [Google Scholar]
- Wolf, C.; Lasser, M. Project IceStorm: Lattice iCE40 FPGAs Bitstream Documentation and Tools. 2017. Available online: https://github.com/YosysHQ/icestorm (accessed on 16 August 2025).
- Wang, Y.; Zhao, C.; Shi, Z. Adaptive Online Neural Predictive Control of Hydraulic Actuator Using FPGA Acceleration. IEEE Trans. Ind. Electron. 2023, 71, 3924–3934. [Google Scholar] [CrossRef] [Scilit]
- Khalil, K.; Kumar, A.; Bayoumi, M. Reconfigurable hardware design approach for economic neural network. IEEE Trans. Circuits Syst. II Express Briefs 2022, 69, 5094–5098. [Google Scholar] [CrossRef] [Scilit]
- Naveen, C.; Chauhan, S.S.; Paramasivam, C.; Meena, V.P. FPGA IP core for DC motor control with adaptive neural network PID tuning, and high-resolution encoder interface. IEEE Access 2024, 12, 169356–169369. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.