


Abstract
With the growing accessibility of tools such as online surveys and web scraping, longitudinal social network data are more commonly collected in social science research along with non-network survey data. Such data play a critical role in helping social scientists understand how relationships develop and evolve over time. Existing dynamic network models such as the Stochastic Actor-Oriented Model and the Temporal Exponential Random Graph Model provide frameworks to analyze traits of both the networks and the external non-network covariates. However, research on the dynamic latent space model (DLSM) has focused mainly on factors intrinsic to the networks themselves. Despite some discussion, the role of non-network data such as contextual or behavioral covariates remain a topic to be further explored in the context of DLSMs. In this study, one application of the DLSM to incorporate dynamic non-network covariates collected alongside friendship networks using autoregressive processes is presented. By analyzing two friendship network datasets with different time points and psychological covariates, it is shown how external factors can contribute to a deeper understanding of social interaction dynamics over time.
1. Introduction
Network analysis is a valuable tool for examining both the traits of individual entities (i.e., actors or nodes) and the relationships (i.e., edges or links) among them. Network analysis has been widely applied across disciplines. For example, in information system research, citation networks are often used to show the evolution of specific research topics, and recent studies have used this method to investigate significant growth of domains like AI-supported learning and biomedical research [1,2]. In social psychology, social network analysis is also widely used to identify social structures and understand risk factors associated with specific behaviors [3,4]. Relevant research has also used social network analysis to uncover the relationships between friendship and personality [5,6,7]. In epidemiology, network analysis can also be useful in modeling and understanding how contagious diseases transmit [8,9].
Among various applications of networks, social networks represent a particularly important class of networks as they capture patterns of social interaction and interdependence among individuals. In recent years, areas of social sciences have seen a shift from using cross-sectional social network data to using longitudinal social network data. This shift is partly driven by increasing interest in understanding how relationships change over time [10,11]. It is also influenced by the growing use of web-based data collection tools, such as web scraping and digital surveys, which simplify the collection of repeatedly measured network data. The increasing usage of longitudinal network data facilitates the application of time-series analysis to social networks. This allows researchers to examine dynamic social network analysis more closely and identify mechanisms of relationship evolution.
Previous research has provided multiple options for analyzing dynamic social networks. One example is the dynamic latent space model (DLSM), which reduces social networks into lower-dimensional representations and then uses the lower-dimensional representations for time-series analysis [12,13]. Other options for modeling dynamic social networks include the temporal exponential random graph model (TERGM) [14] and the stochastic actor-oriented model (SAOM) [15]. The TERGM and the SAOM both explain changes in a time series of social networks through a combination of network statistics. In the frameworks of both models, changes from time point to time point are exclusively related to the changes in certain network statistics. These network statistics can include those intrinsic to the networks, such as reciprocity, which refers to the phenomenon where relationships in both directions are present between a pair of actors in a directed network. Additional covariate-related statistics can also be included, such as homophily, which refers to the situation that nodes with closer values of covariates tend to connect. The key difference between TERGM and SAOM lies in how network changes related to the network statistics are conceptualized and analyzed. TERGM models changes at the level of the entire network for each discrete time point. For example, reciprocity is calculated as the total number of reciprocated pairs of actors across the whole network, and then it is used to capture differences across time points. In contrast, SAOM analyzes changes at the level of individual actors, where reciprocity is defined as the number of reciprocated ties connected to a given actor [16]. Changes in reciprocity are then analyzed with respect to mini-steps, in which actors make choices in terms of continuous time. For dynamic network analysis with the goal of community detection, the dynamic stochastic block model (DSBM) can be a satisfactory option [17].
The different dynamic social network models, including TERGM, SAOM, DSBM, and DLSM, reflect different theories behind social networks. Thus, the decision of which model to use often depends on specific hypotheses proposed in each research scenario. For example, the DSBM is often used for dynamic community detection. Compared to TERGM and SAOM, the LSM approach to dynamic social network analysis has its advantage in incorporating actor-based network structures naturally into the latent positions as well as the ease in visualization [13], but it has its disadvantage in the difficulty in interpretations as all effects intrinsic to the networks are represented by the latent positions [18].
Non-network covariates such as demographic characteristics and behavioral patterns play vital roles in network tie formation processes [19,20,21]. As a result, recent advancements in network sciences have been centered on the co-evolution of non-network covariates with networks, especially from a longitudinal viewpoint. In both the TERGM framework and the SAOM framework, dynamic nodal behavioral attributes can be incorporated as part of the network statistics that these models rely on, although Leifeld and Cranmer [16] argue that covariate behaviors in SAOM might, in general, be more dynamic than those in TERGM since SAOM treats network changes as continuous. For both frameworks, applications assessing dynamic covariates’ effects on network formation have also emerged. For example, Wang et al. [22] evaluate the changing political relations’ effect on trading networks and Rogoza et al. [23] assess the impact of the evolving dark triad personality trait scores on social relationships using TERGM. The tutorial by Kalish [24] illustrates how SAOM can be used to model dynamic networks and behaviors using the example of work turnover and friendship, and Chu et al. [25] use SAOM to model dynamic pandemic-related covariates’ influence on financial network changes. For DSBM, versions incorporating time-varying covariates in clustering network nodes can be found in works such as that by Olivella et al. [26].
The current paper addresses the incorporation of time-varying non-network covariates into the DLSM framework. Parallel to the development of dynamic covariate-related extensions in other network frameworks mentioned above, DLSM has seen some innovations integrating dynamic covariates [27,28]. In these extended models, covariates are treated as inputs for each time point, and their effects on network formation are modeled through time-varying coefficients. However, these approaches leave the temporal dynamics of the covariates themselves largely unmodeled. In contrast, the current study aims to extend upon the DLSM proposed by Sewell and Chen [13] to explicitly model the evolutionary processes of the covariates themselves as autoregressive (AR) processes. As Zhao et al. [29] discussed, compared to using a non-parametric model for the dynamic covariates, using an AR process can provide a more structured way to view the temporal evolution of covariates, capturing how the covariates themselves change instead of how their effects on outcome variables change. In the following sections, the extended DLSM model setup will be presented, followed by its application to two friendship network datasets.
2. Methods
2.1. DLSM and Its Extensions
2.1.1. The Existing Models
LSM was first proposed by Hoff et al. [12] and has been used in modeling cross-sectional social networks. In this model, the log odds of the probability that an edge exists between actor i and actor j in a binary network is proportional to , where is the intercept and is the latent distance between actors i and j. When using the Euclidean distance, . Here, and are the latent position vectors of the actors i and j. The purpose of LSM is to estimate such latent positions so that low-dimensional representations of how close the actors are to each other can be obtained. In the latent space, an edge is more likely to form between pairs of actors that are closer together. LSM has been used in many studies to investigate the effect of social proximity [5,30].
LSM can be extended to explain dynamic social networks by expanding the model to network data with different time points. One DLSM specification was proposed by Sarkar and Moore [31], in which latent positions at a specific time point t, denoted by the vector for actor i, can be viewed as generated from a Markov process that depends only on the latent positions at the previous time point and is transitioned via a normal distribution. The probability of a link in the observed network is , where is the Euclidean distance between and —the latent positions of actor i and j at the time point t—and is a constant. The function can be modified to include radius for each actor i that defines an individual’s social reach, meaning that the extent of forming a link is constrained to some degree.
Sewell and Chen [13] extend the DLSM outlined by Sarkar and Moore [31] to include parameters for an individual’s popularity and social activity. The modified model has the following specification as shown in Equations (1)–(3). In this specification, latent positions , which is a vector at the first time point, follow a multivariate normal distribution, as shown in Equation (2). Latent position coordinates at the first time point have a mean of and are independent across dimensions so that the covariance matrix is diagonal with the variance parameter being the spread of latent position coordinates. A larger would mean that latent positions are farther apart from each other at the first time point. Latent positions at a latter time point t can be seen as formed by adding a random component to the latent positions at the previous time point (Equation (3)). The random component follows a multivariate normal distribution with mean and diagonal covariance matrix , where represents the movement parameter of latent position coordinates from one time point to another. A larger means that latent position movements from time point to time point are larger. In Equation (1), is the coefficient representing the importance of the popularity of an actor who is a recipient of a social relationship, and represents the importance of the sender being active in seeking friends. The parameters and are the social reach parameters for the two individuals forming the edge. The distance can be flexibly defined. Commonly, the Euclidean distance is used. Using and as predictors means that the predictors’ values increase with the decrease in the distance () between two actors as well as the increase in social reach ( and ) of each actor. Therefore, when both and are positive, the probability of tie formation increases with a decreasing distance between two actors and an increasing social reach.
In the case when , it would be reasonable to assume and such that social activity is more important than popularity, and the term governs the increase in edge probability over the influence of the term on decreasing tie probability when the predictors increase [13]. The case where and can be interpreted vice-versa. When both and are negative, this contradicts the theory behind LSMs such that a smaller distance between latent positions would correspond to a higher probability of forming a relationship, and is therefore not considered.
To account for dynamic covariates more flexibly, Adhikari et al. [27] proposed a DLSM with dynamic covariates with a link function in the form of Equation (4), where denotes a sender effect on node i, denotes a receiver effect on node j, denotes the relationship between the network edge and the covariate , which is the qth edge-wise covariate at time t. In this model, the coefficient varies with time point, making the relationship between covariates and network edge a dynamic component. Loyal [28] utilizes a similar model, but instead of using the coefficient to link covariates with network edges, a real-valued function is used for estimating non-parametric relationships between the dynamic networks and the dynamic covariates.
2.1.2. DLSM with Covariate Evolution
The implementations of the DLSM with time-varying covariates by Adhikari et al. [27] and Loyal [28] primarily focused on the changing covariate effects on dynamic network formation. However, the evolution of the covariates themselves is not incorporated in the models. In social science research, the change in non-networks themselves is often of interest as well. The current study aims to not only investigate the covariate effect in DLSM but also account for covariate evolution alongside network evolution. Instead of modeling the covariate effect as time-varying like in Adhikari et al. [27] and Loyal [28], the covariate evolution itself will be modeled as an autoregressive process when keeping the covariate effect on the network constant across time. This model specification allows the changing covariate effect on the network to be a result of the covariates’ own varying level across time instead of the effect itself changing.
The proposed actor-based covariate evolution model is shown in Equations (5)–(8). The model assumes that the actor-based covariate vector has individual covariates each following an AR(1) autoregressive process, as shown in Equation (6). In this case, and are all vectors of length Q for Q different covariates. forms a diagonal matrix from the vector . An intercept term is not included for simplicity, and thus corresponding covariates should be centered. Here, a smaller would suggest that the covariate of the current time point is less dependent on itself at the previous time point. It is assumed that different covariates can have different autoregressive coefficients and shock variable variances, but their autoregressive processes are independent of each other. This simplification of autoregressive processes of the covariates is not only done to ease the interpretation of the model but also to be consistent with the latent position model specification as the latent positions of different dimensions are assumed to evolve independently. The Markov process for the latent position is unchanged from the DLSM without covariates, as shown in Equations (7) and (8), while the log odds of the probability of a link in the social network is modified to include the term , where is a vector of customizable function with each measuring the difference or distance between the covariate values of two individuals for the qth covariate. This function produces separate difference measures for each covariate so that the coefficient is also a vector of dimension Q containing all Q coefficients for . This is chosen over an overall covariate difference measure over all covariates to distinguish potentially different effects of different covariates. When , each element of corresponds to the effect of the difference score such that a larger indicates a more likely relationship between a pair of sender and receiver if the sender has a higher covariate value than the receiver. This signed difference score will be used in the data analyses in this study.
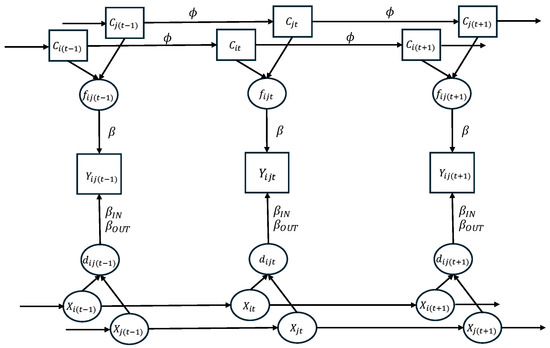
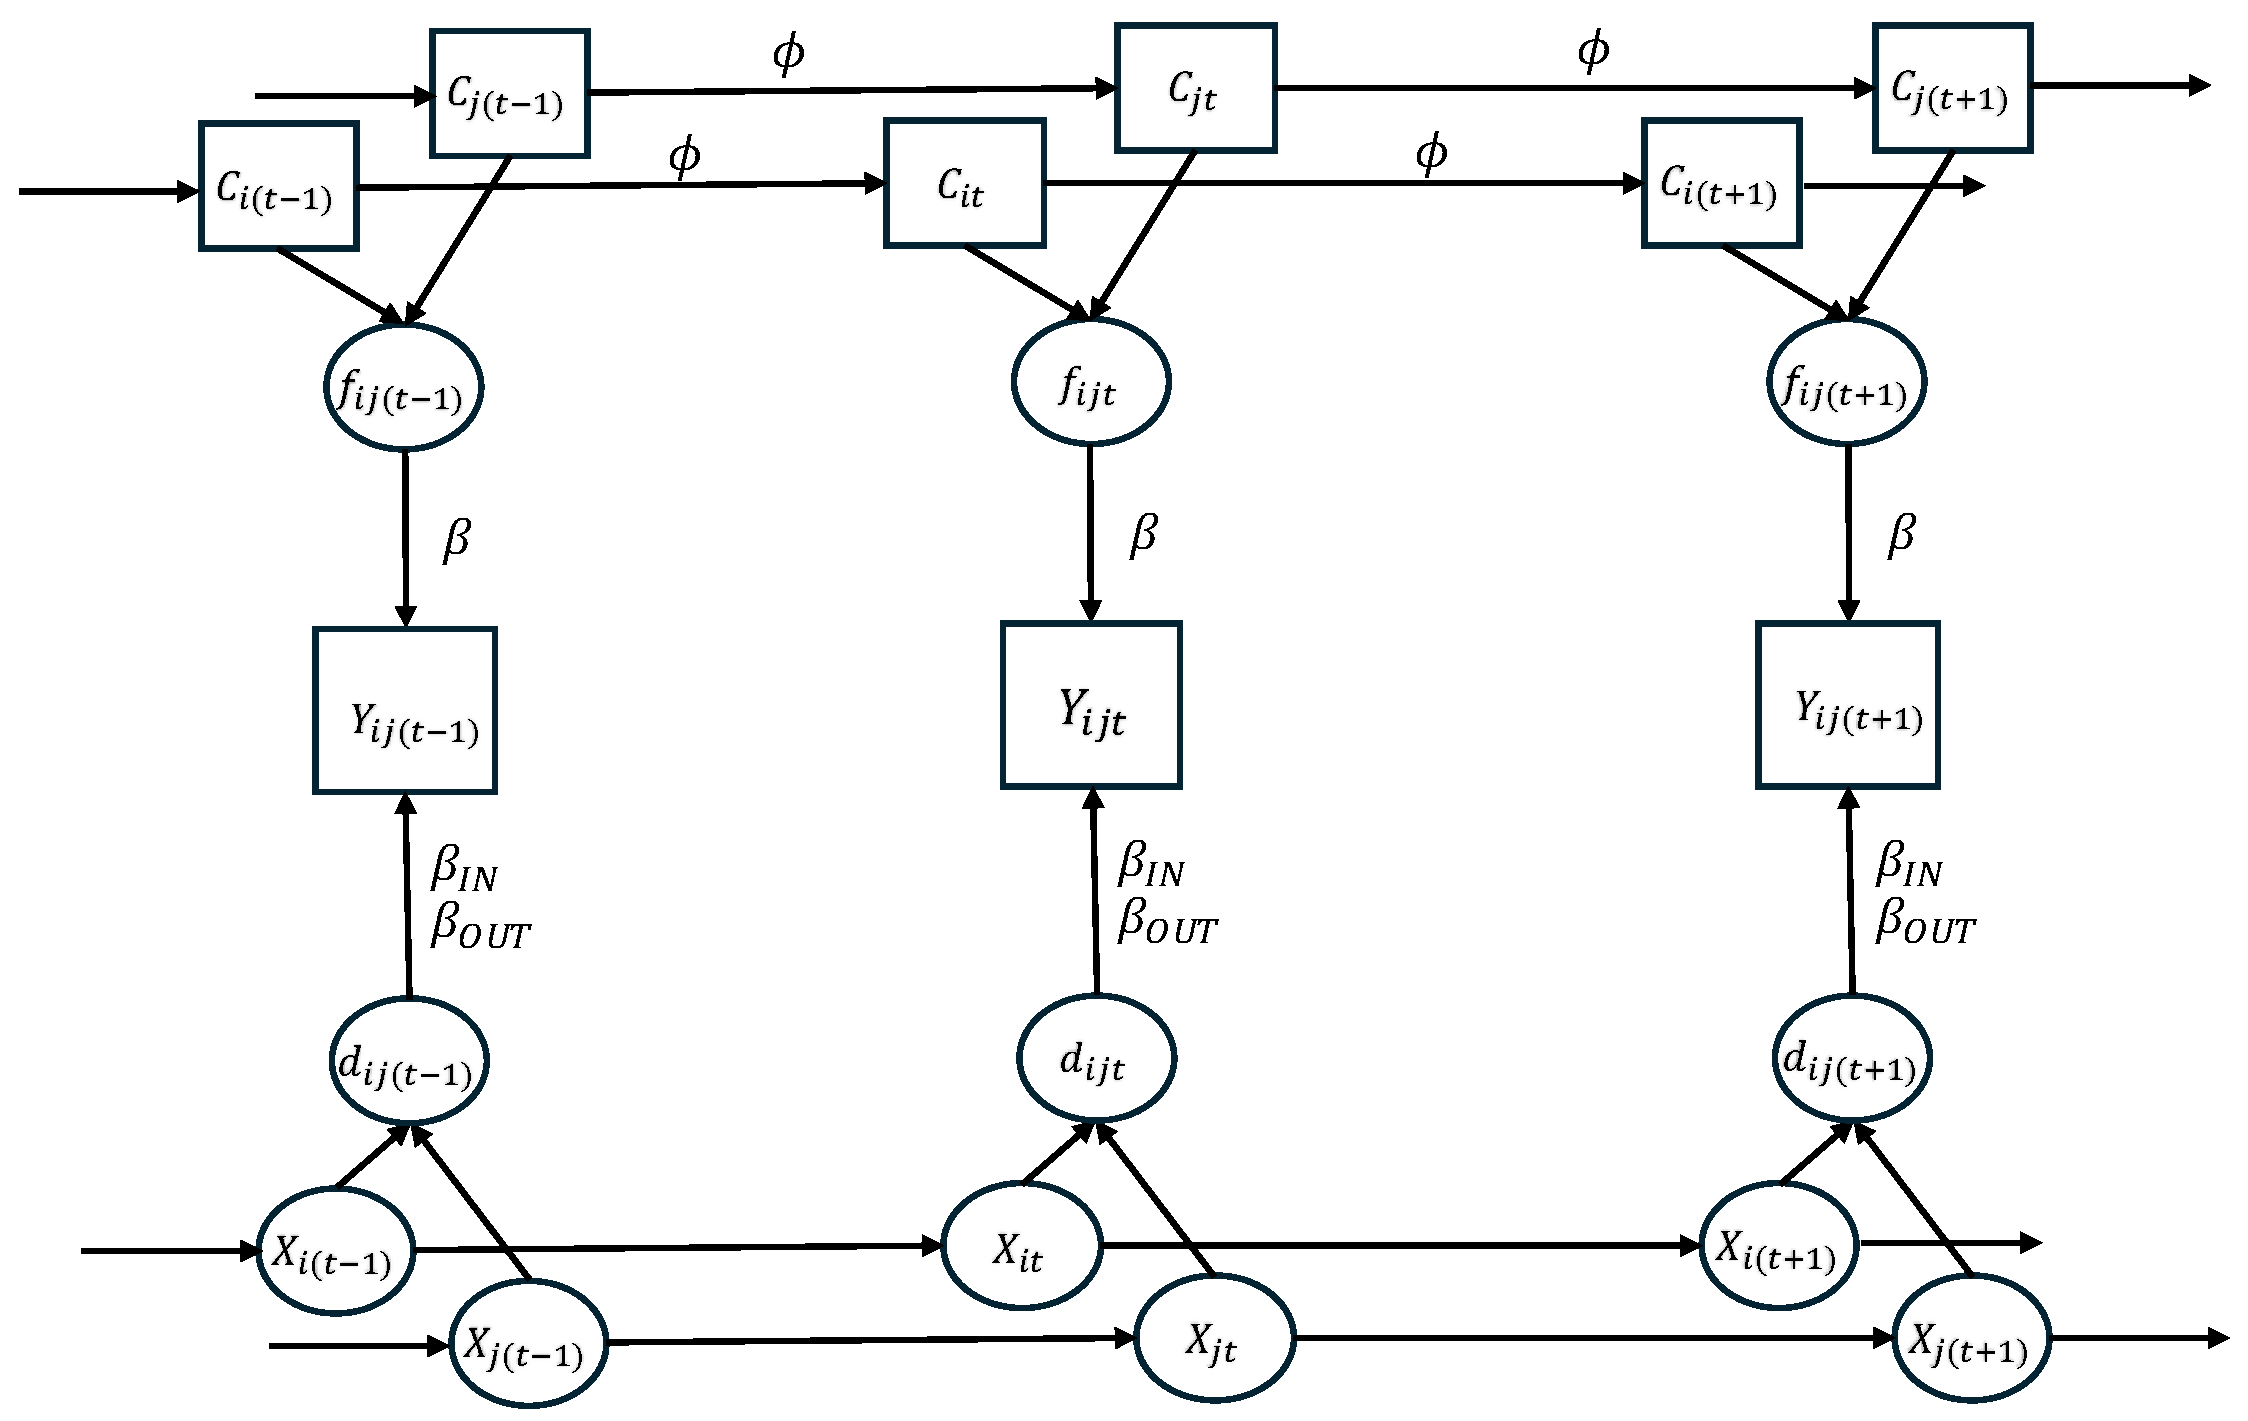
The actor-based covariate evolution model with one covariate is visualized in Figure 1. Because only one covariate is included, vectors , , , and are reduced to scalars and are represented by , , , and . In this representation, represents the actor-based covariate value at time t for individual i, and represents the actor-based covariate value at time t for individual j. The covariate evolves over time with the AR parameter , indicated by the arrows from the previous time point to the next time points for the covariate. The latent positions are represented by and for individuals i and j at time t, which also evolve over time as indicated by the arrows connecting latent positions at different time points. When focusing on a specific time point t, the covariate difference value and the latent distance both contribute to the observed network edge .
Figure 1.
DLSM with actor-based covariate evolution. is the covariate value for actor i at time t, is the latent position of actor i at time t. and represent the pairwise latent distance and covariate difference at time t, and represents the observed edge at time t between actors i and j. The noise components in both the covariate AR process and the latent distance process are hidden for simplicity.
2.2. Estimation of Model Parameters
For the covariate evolution model, a Bayesian approach extending Sewell and Chen [13] can be used for model estimation. Time-varying actor-based covariates can be incorporated into the process and sample the parameters with the assumption of T time points, n network nodes, and p latent position dimensions. The logistic link parameters as well as the latent position are estimated using the Metropolis–Hastings (MH) algorithm, while the rest of the parameters, including , and are estimated using Gibbs sampling schemes. Here, we use subscripts to denote a generic scalar parameter corresponding to the covariates. For example, refers to any in vector . The issue of latent positions being not uniquely identified is quite commonly solved in the LSM literature by using the Procrustes transformation. In our estimation, the approach outlined by Sewell and Chen [13] is used. Estimated latent positions are aligned with a chosen set of coordinates to make sure latent positions are well defined.
The estimation of parameters , and can be modified based on the sampling scheme in Sewell and Chen [13] by updating the likelihood of edge formation to include the covariate effect, as shown in Equation (9).
Using the above edge formation likelihood, conditional distributions in Equations (10)–(13) can be derived in the MH sampling processes for , , , and , respectively. In these equations, denotes the collection of all the parameters the current parameter is being conditional on. Specifically, in Equation (12) and in Equation (13) are the normal priors for and , whereas a Dirichlet (1,…,1) distribution is used as the prior for the social reach r.
The parameters , and can be sampled with the following schemes, as shown in Equations (14) and (15). In this case, the prior for is and for is .
The covariate effects have the conditional distribution, as shown in Equation (16), with being the prior of the covariate effects. Since this is a parameter added in the extension model, the derived acceptance ratio is shown as in Equation (17), where is the log of the acceptance ratio in each iteration of the MH sampling process and the superscripts and indicate the value of the covariate effect in the previous and the current iterations. The covariate effect corresponding to each covariate is updated separately in this process. In Equation (17), the MH scheme is simplified to have only one covariate.
For covariate evolution parameters and , the conditional distributions are given below in Equations (18) and (19). In these two equations, it is also assumed that there is only one covariate for simplicity of the notations. The prior of is assumed to be , and the prior of is assumed to be .
Further prior and initialization value choices are shown in Table 1. For parameters , initial values and priors are chosen according to Sewell and Chen [13]. Prior and initial value for are chosen based on the maximum likelihood estimates, and weak informative priors and initial values for , and are used. Only one set of estimated optimal initial values is considered in this case because of the computation cost and the identification issues that arise from the latent space: if latent positions are not consistent across chains, estimates may not converge.
Table 1.
Priors and initial values used in estimating parameters of the extended DLSM.
With the derived Bayesian likelihoods and posteriors for parameters added in the extended DLSM along with sampling steps above, the sampling process is implemented in R [32] with packages Rcpp [33] and RcppArmadillo [34]. The R code modifying code from Sewell and Chen [13] to include AR processes for covariates can be found on Github at https://github.com/xzqziqian/DLSMcov, accessed on 27 January 2026.
3. Applications
3.1. Data
3.1.1. Overview of Dataset 1
Dataset 1 was collected via weekly surveys from September 2021 to April 2022 with 30 time points () from a university in south China with after data cleaning. Participants from a single classroom were recruited at the beginning of the data collection, and no new participants entered in the following waves of data collection. Missing data percentages for the friendship network ranges from 18.6% to 31.4% for each time point. Friendship information in this dataset was collected on a Likert scale with responses of Dislike, Neither Like or Dislike, Friend, Good Friend, and Best Friend. In the analysis, responses to the first two categories are coded as a lack of friendship and the other three categories as an existence of friendship.
Besides questions regarding friendship, information about respondents’ smoking and drinking behaviors, overall happiness, and perceived pressure levels were also collected. Bayesian estimation of the extended DLSM will be carried out on this dataset with the self-report values of three covariates: (1) compared to last week, I attended more social events; (2) compared to last week, I feel happier this week, and (3) compared to last week, I feel more pressure this week. Participants reported their scores on these three Likert-scale covariates on a scale of 1 (highly disagree) to 5 (highly agree). Covariates were centered to be used in the extended DLSM, and the function was used to investigate whether person i, or the sender of a friendship, is more likely to form a friendship with person j or the receiver of a friendship, with a lower or higher covariate score than the sender themselves.
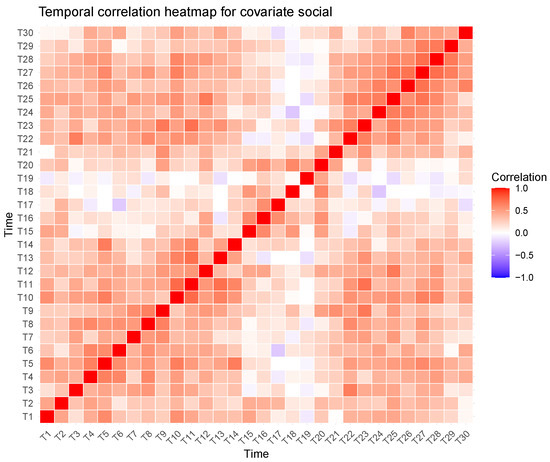
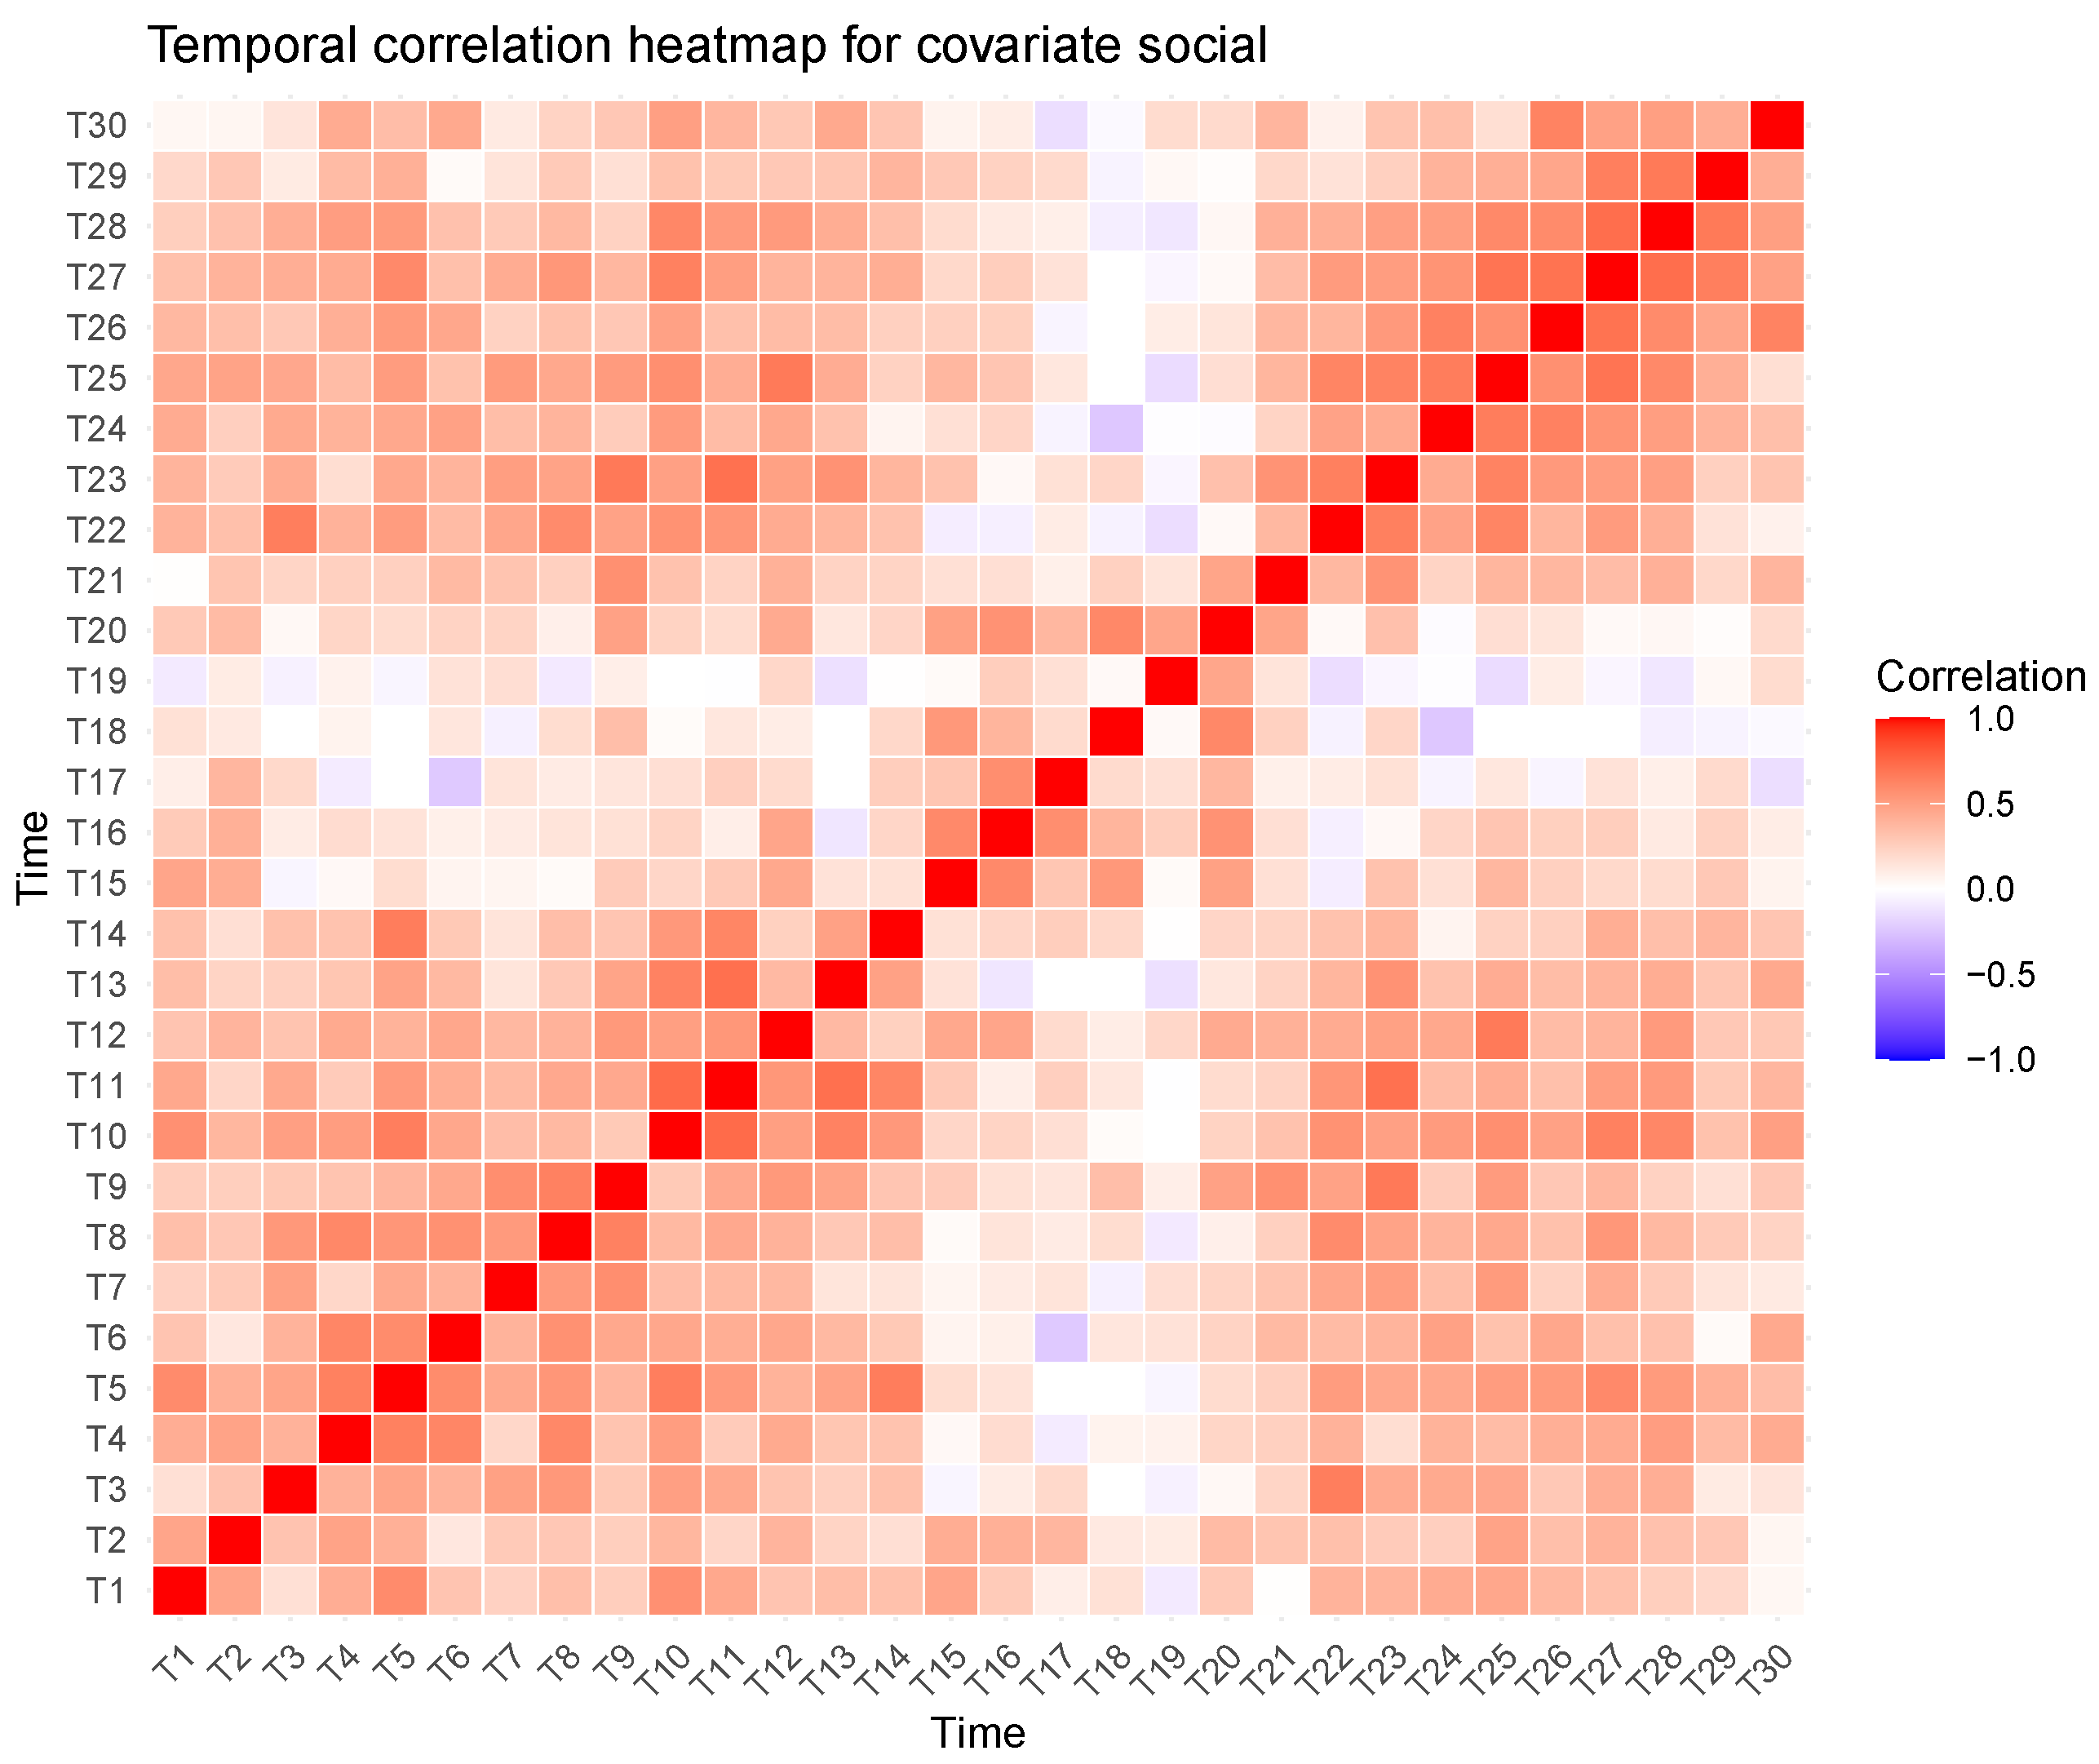
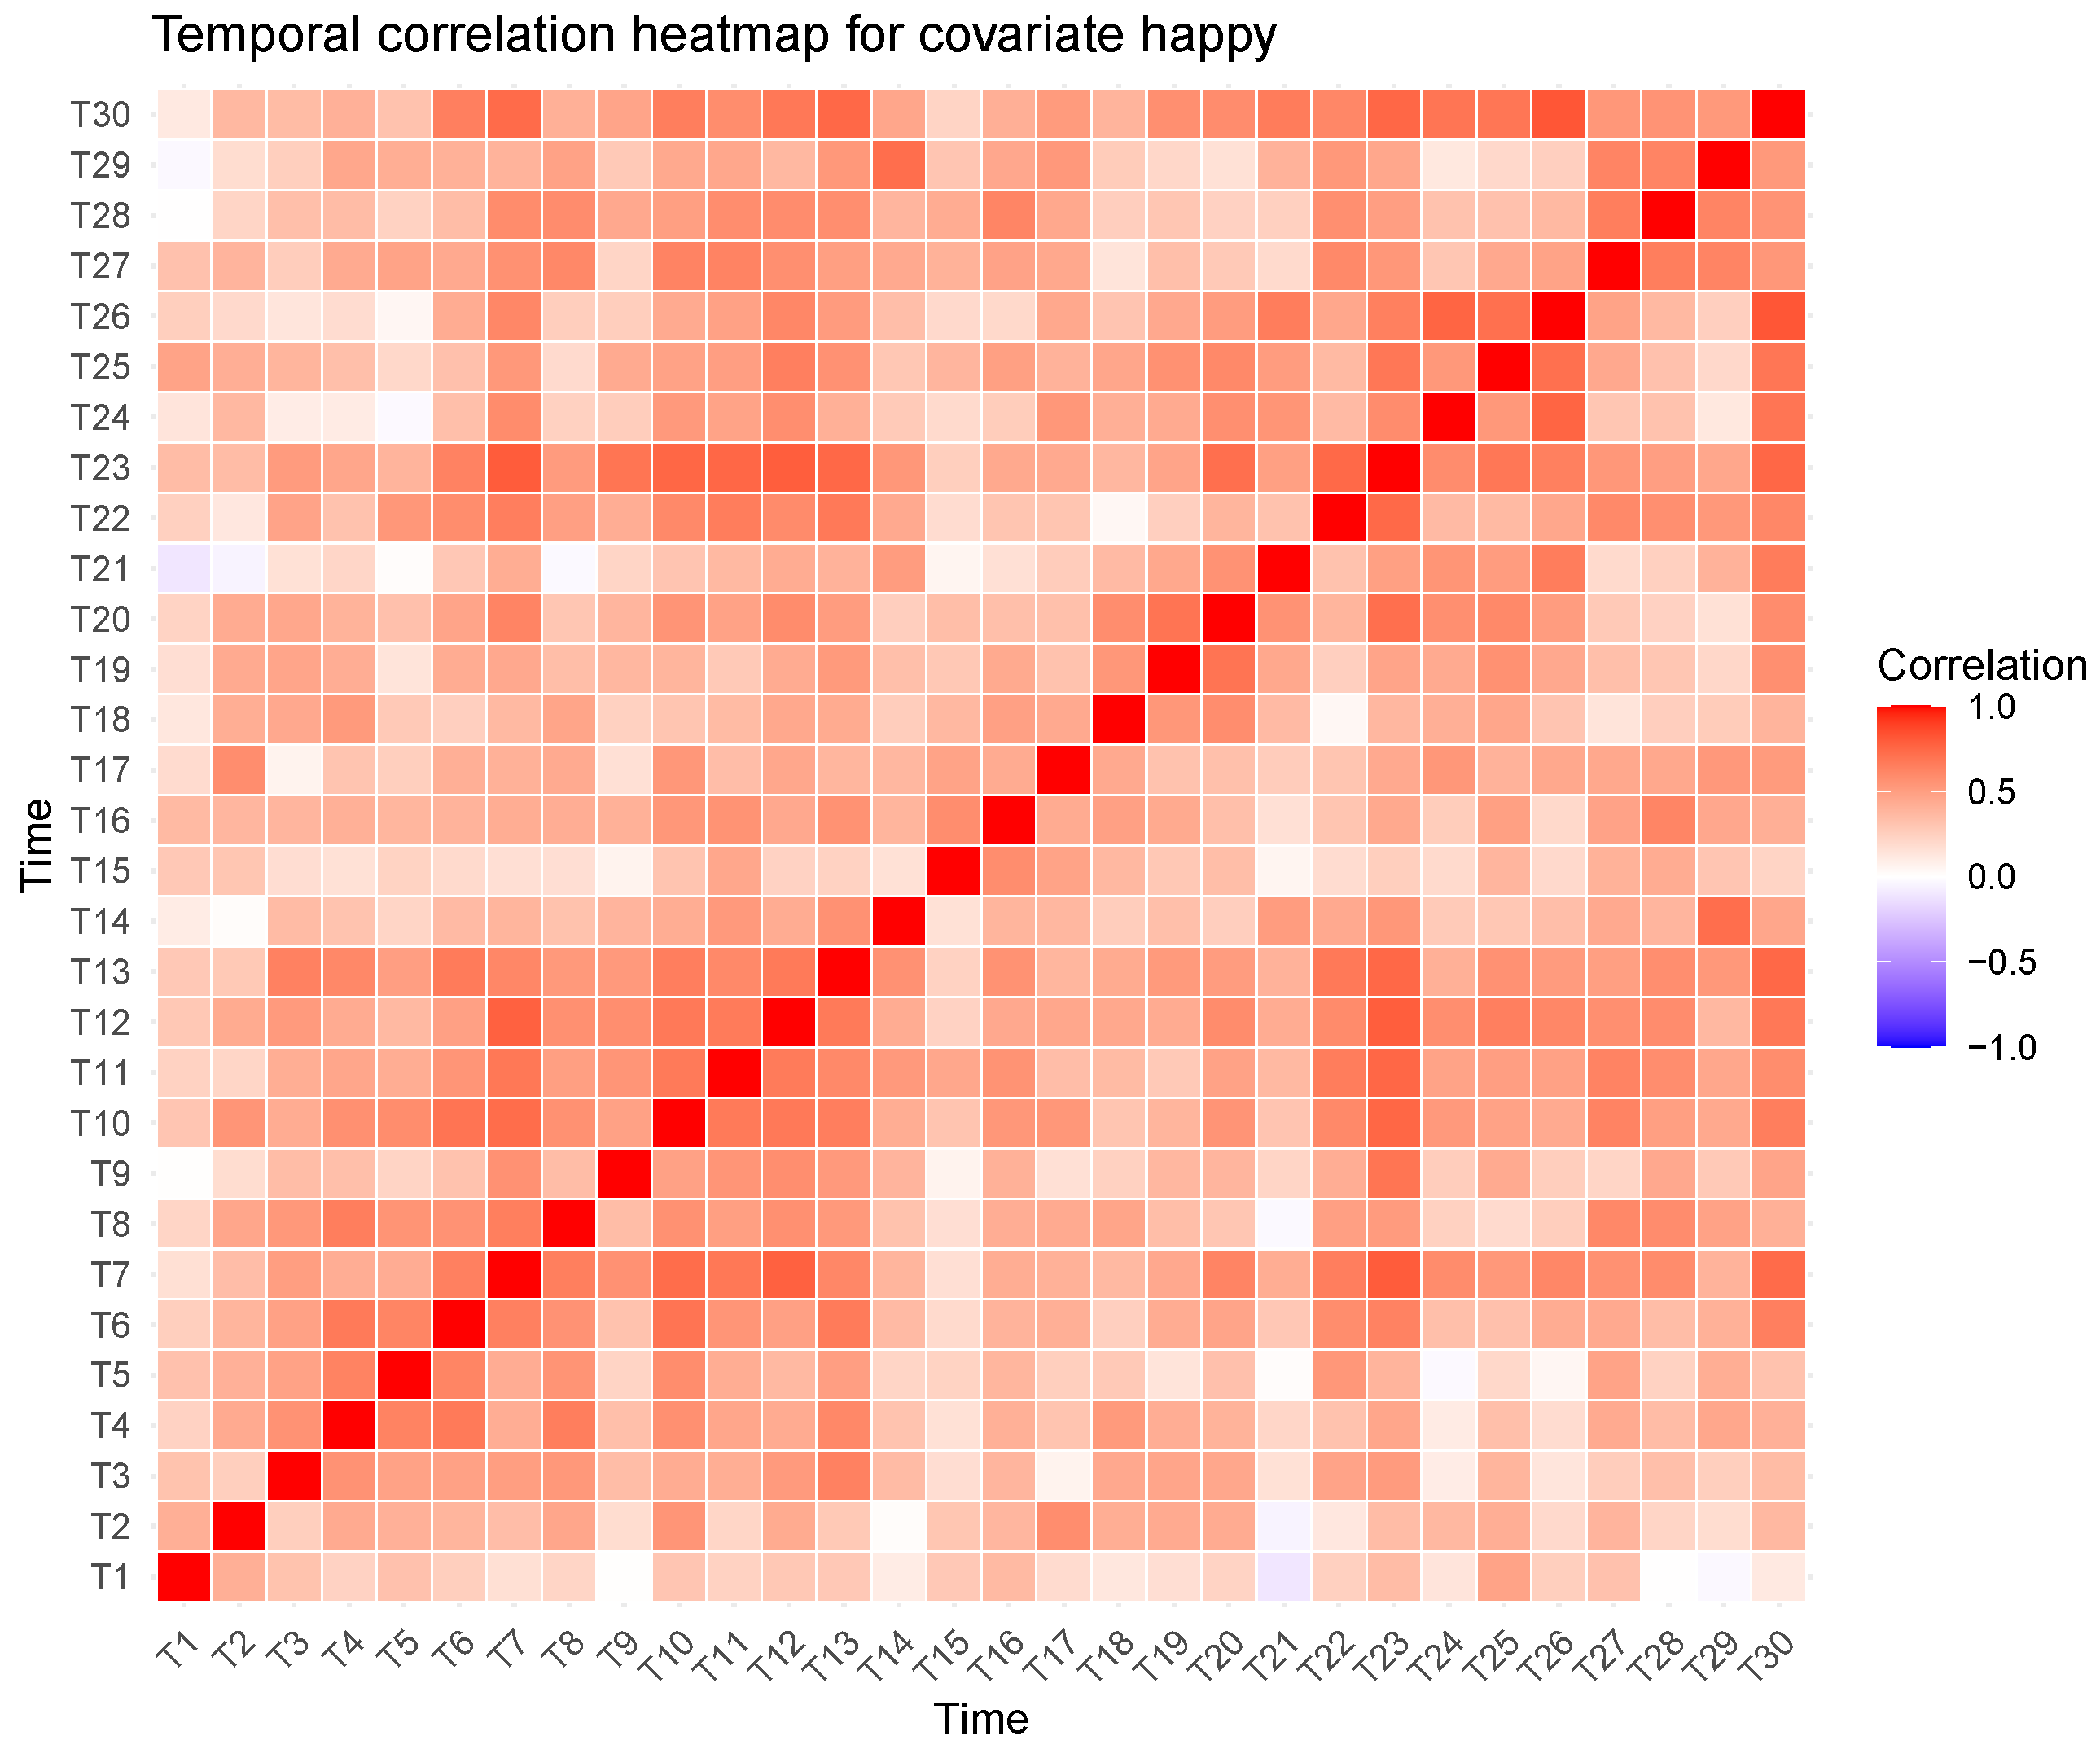
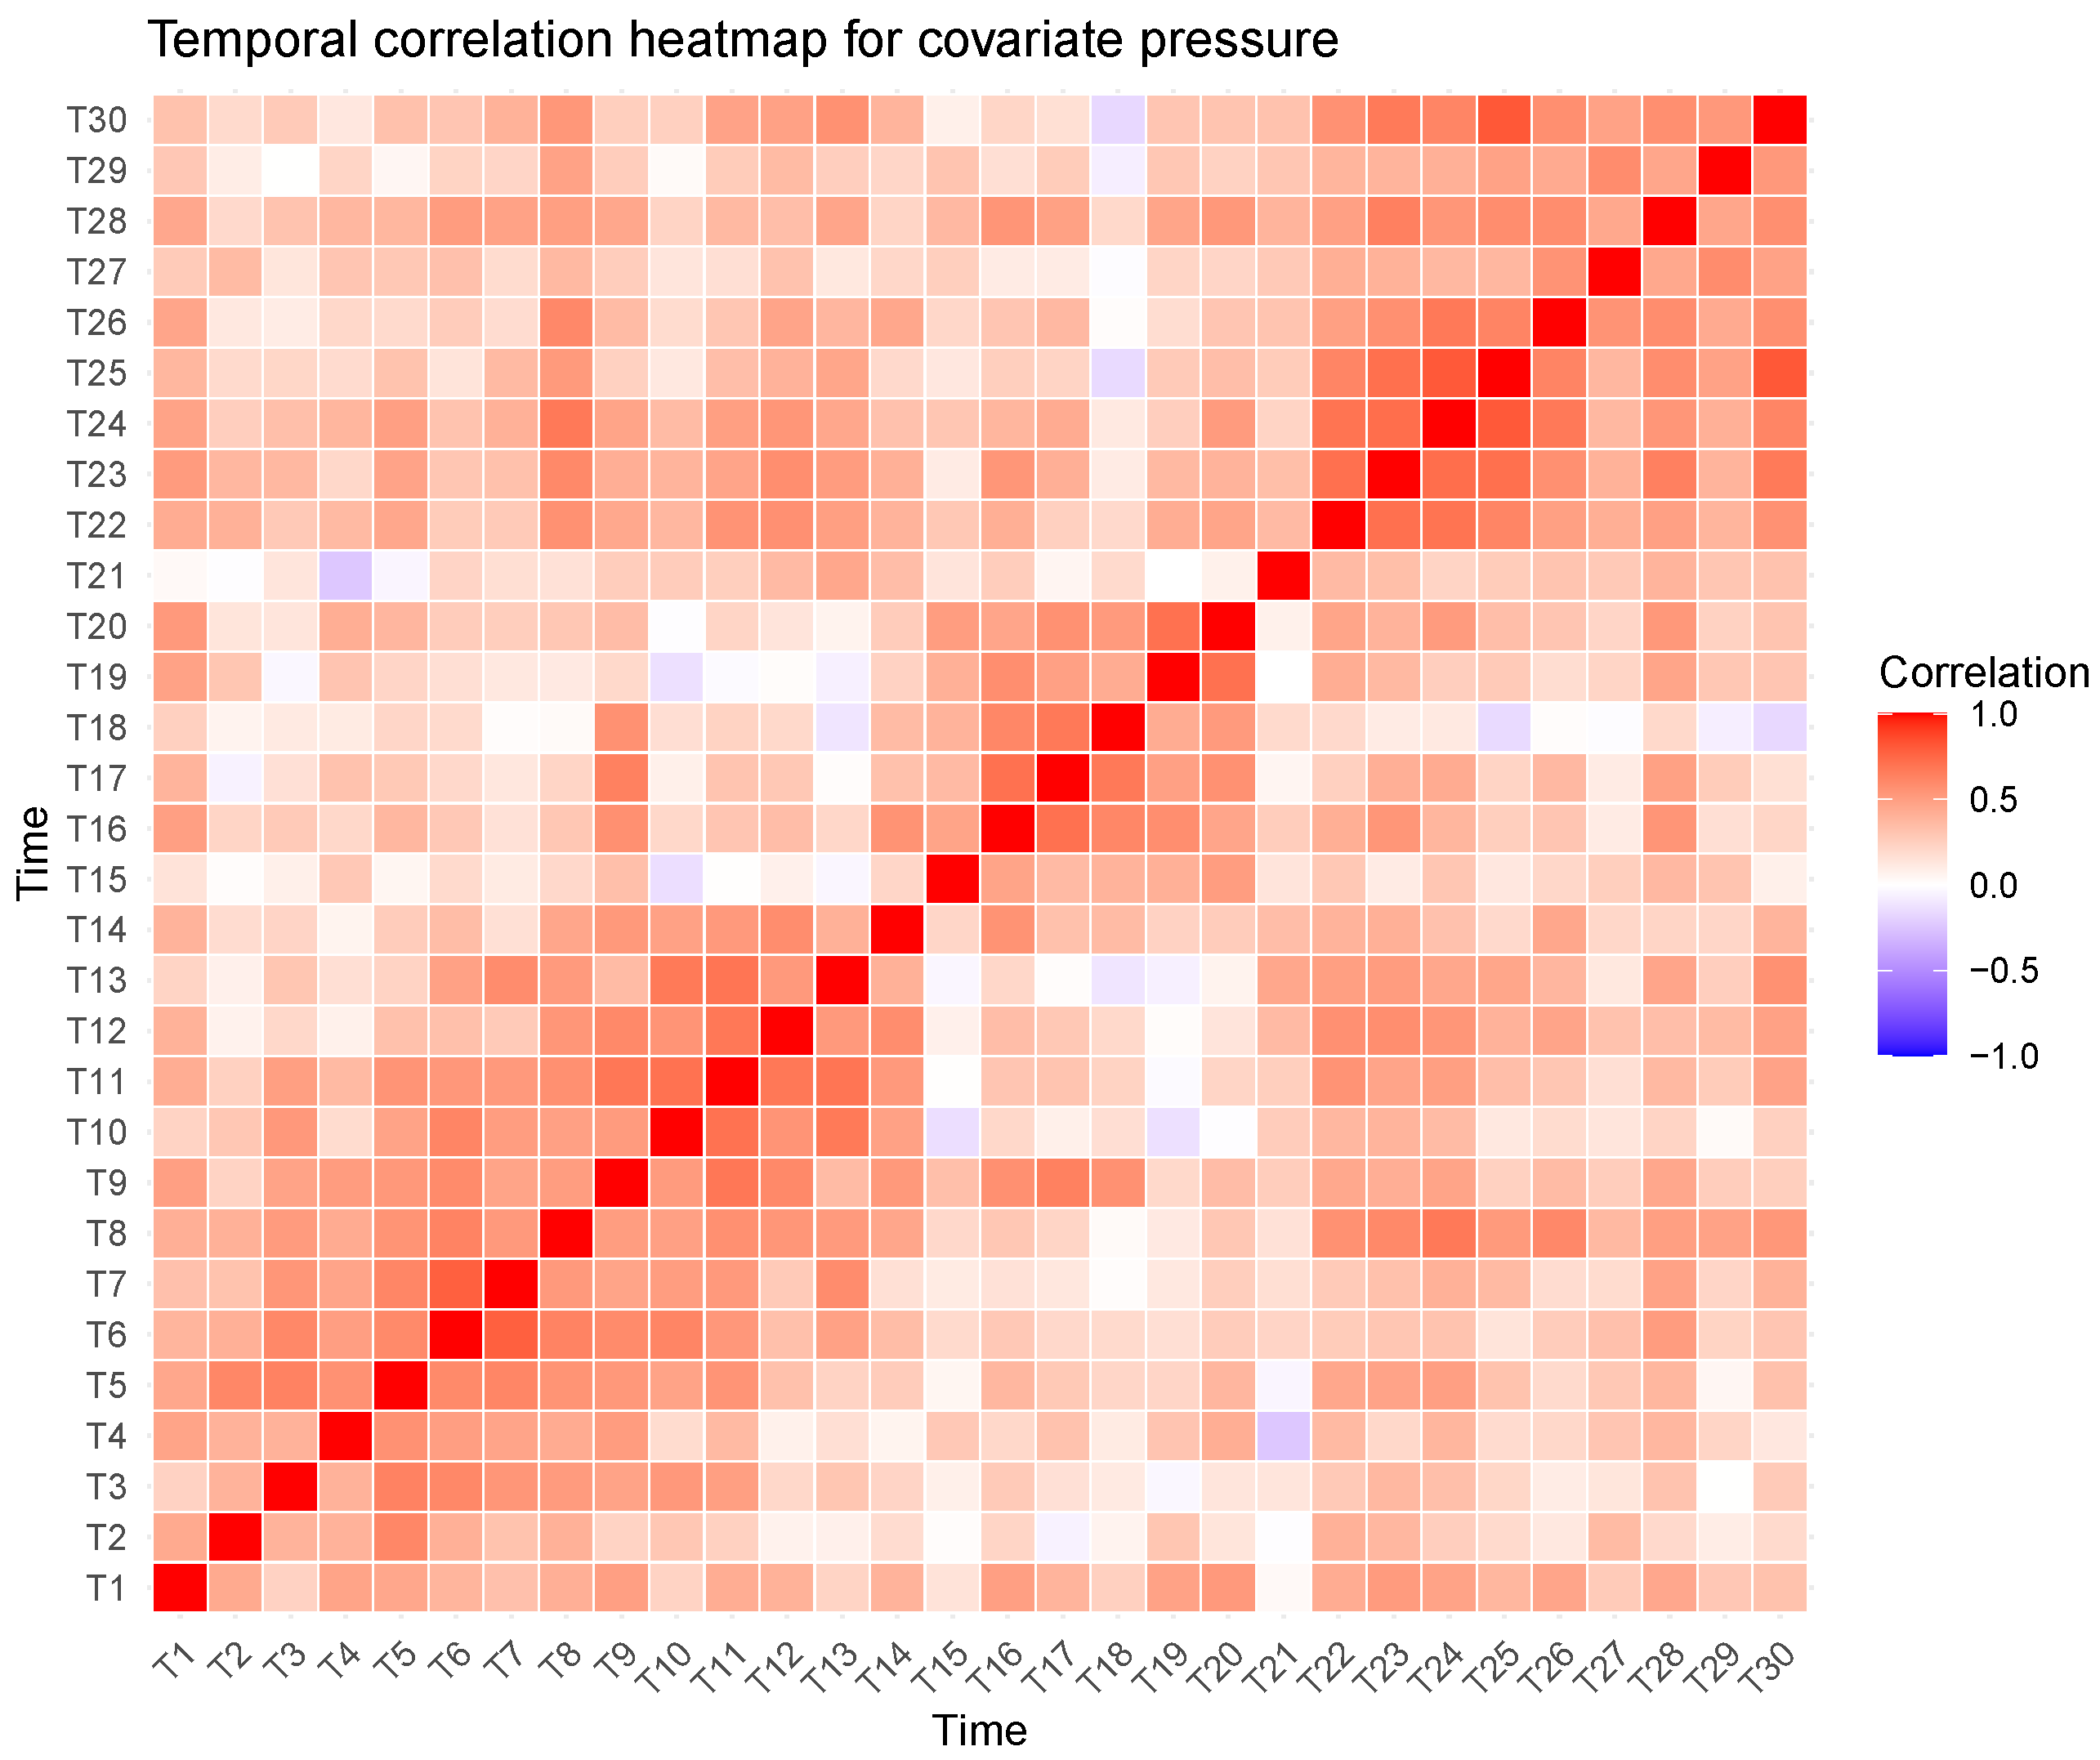
At each time point, the correlations among social event attendance, happiness, and pressure ranged between −0.36 and 0.716. The temporal correlations for the three covariates are shown in Figure 2, Figure 3 and Figure 4. The maximum variance inflation factor between the two covariates across time points is 2.49, suggesting no multicollinearity.
Figure 2.
Temporal correlations of the covariate social event attendance.
Figure 3.
Temporal correlations of the covariate happy.
Figure 4.
Temporal correlations of the covariate pressure.
3.1.2. Overview of Dataset 2
A second dataset was collected yearly from 2017 to 2019 in a Chinese university with after cleaning. For covariates, loneliness and the extroversion personality trait were used. In this dataset, loneliness was measured with 10 items in the UCLA loneliness scale, with Likert responses of 0: Never, 1: Rarely, 3: Sometimes and 3: Often [35]. For extroversion, the Mini-IPIP scale with 4 items of Likert responses from 1 (Strongly Disagree) to 5 (Strongly Agree) was used [36]. The covariates were, again, centered to be used in the analysis.
We use extroversion and loneliness as covariates in this analysis by taking the mean score after reverse coding appropriate items. Network responses were collected on a Likert scale with responses of 0: I have heard of their names, 1: I heard about the person but have had no interaction with them, 2: I have met the person a few times but we are not friends, 3: the person is a friend of mine, and 4: the person is one of my best friends. For the analysis, networks are dichotomized so only responses 3 and 4 are considered as friendship ties.
At each time point, the correlations between loneliness and extroversion are −0.052, −0.078, and −0.133. The temporal correlations for loneliness and extroversion are shown in Table 2 and Table 3. The variance inflation factors between the two covariates at each time point are 1.003, 1.006, and 1.018, suggesting no multicollinearity.
Table 2.
Temporal correlation for loneliness.
Table 3.
Temporal correlation for extroversion.
3.2. Analysis
Both Dataset 1 and Dataset 2 are analyzed with the covariate informed DLSM under a Bayesian framework, with posterior inference carried out using code adapted from Sewell and Chen [13]. Trace plots for MCMC samples and Geweke z-scores were obtained for convergence analysis of corresponding parameters. After convergence analysis, mean parameter values with 95% credible intervals for estimated coefficients were obtained and reported. Finally, to evaluate predictive performance, receiver operating characteristic (ROC) curves and precision–recall curves were constructed for each dataset to predict edges. The area under the ROC curve (AUC) was used as a summary measure of the model’s discriminative ability across classification thresholds. AUC was compared between the DLSM with covariates and a DLSM without covariates as the baseline model.
3.3. Results
3.3.1. Results of Dataset 1
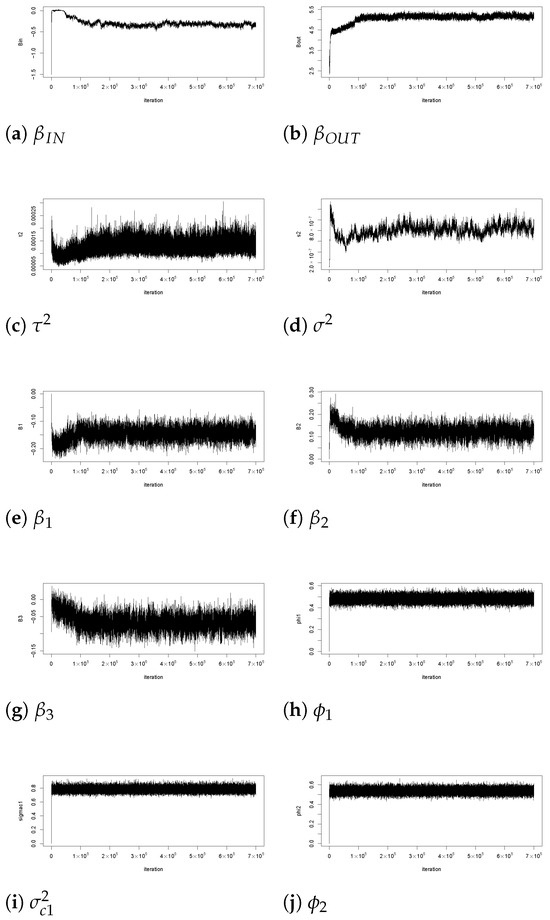
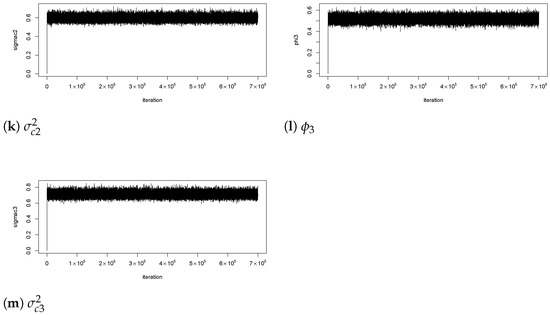
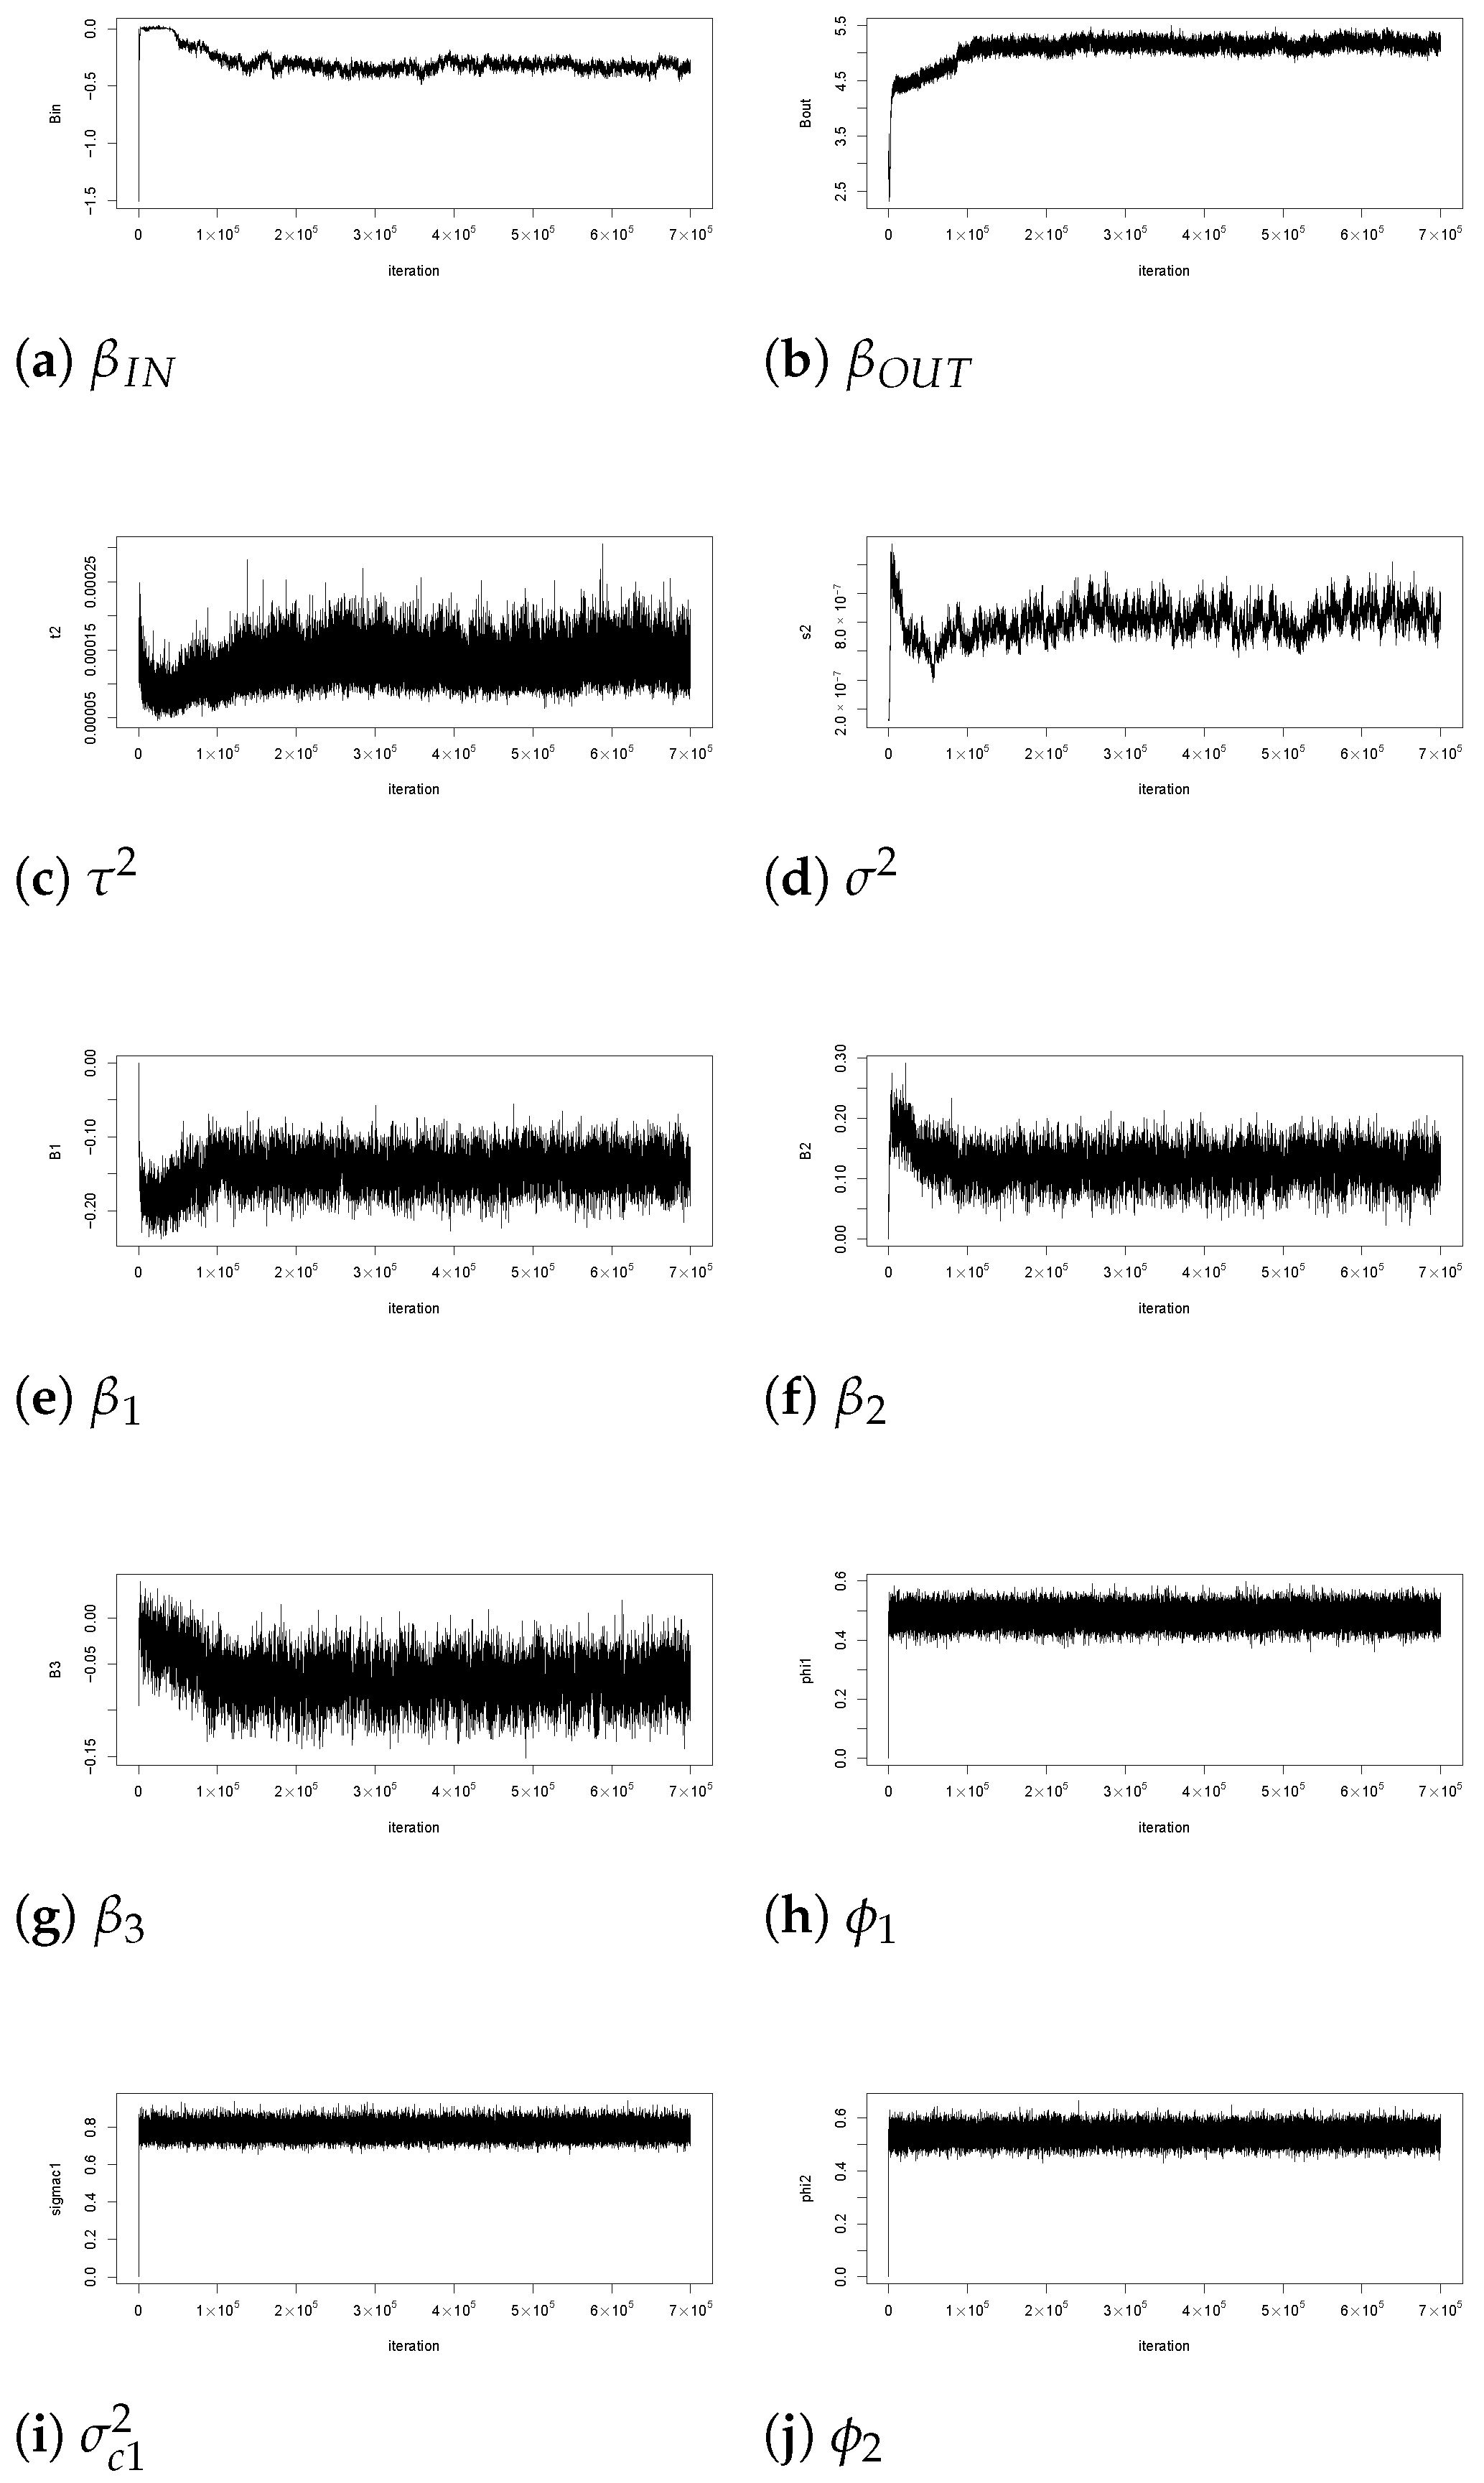
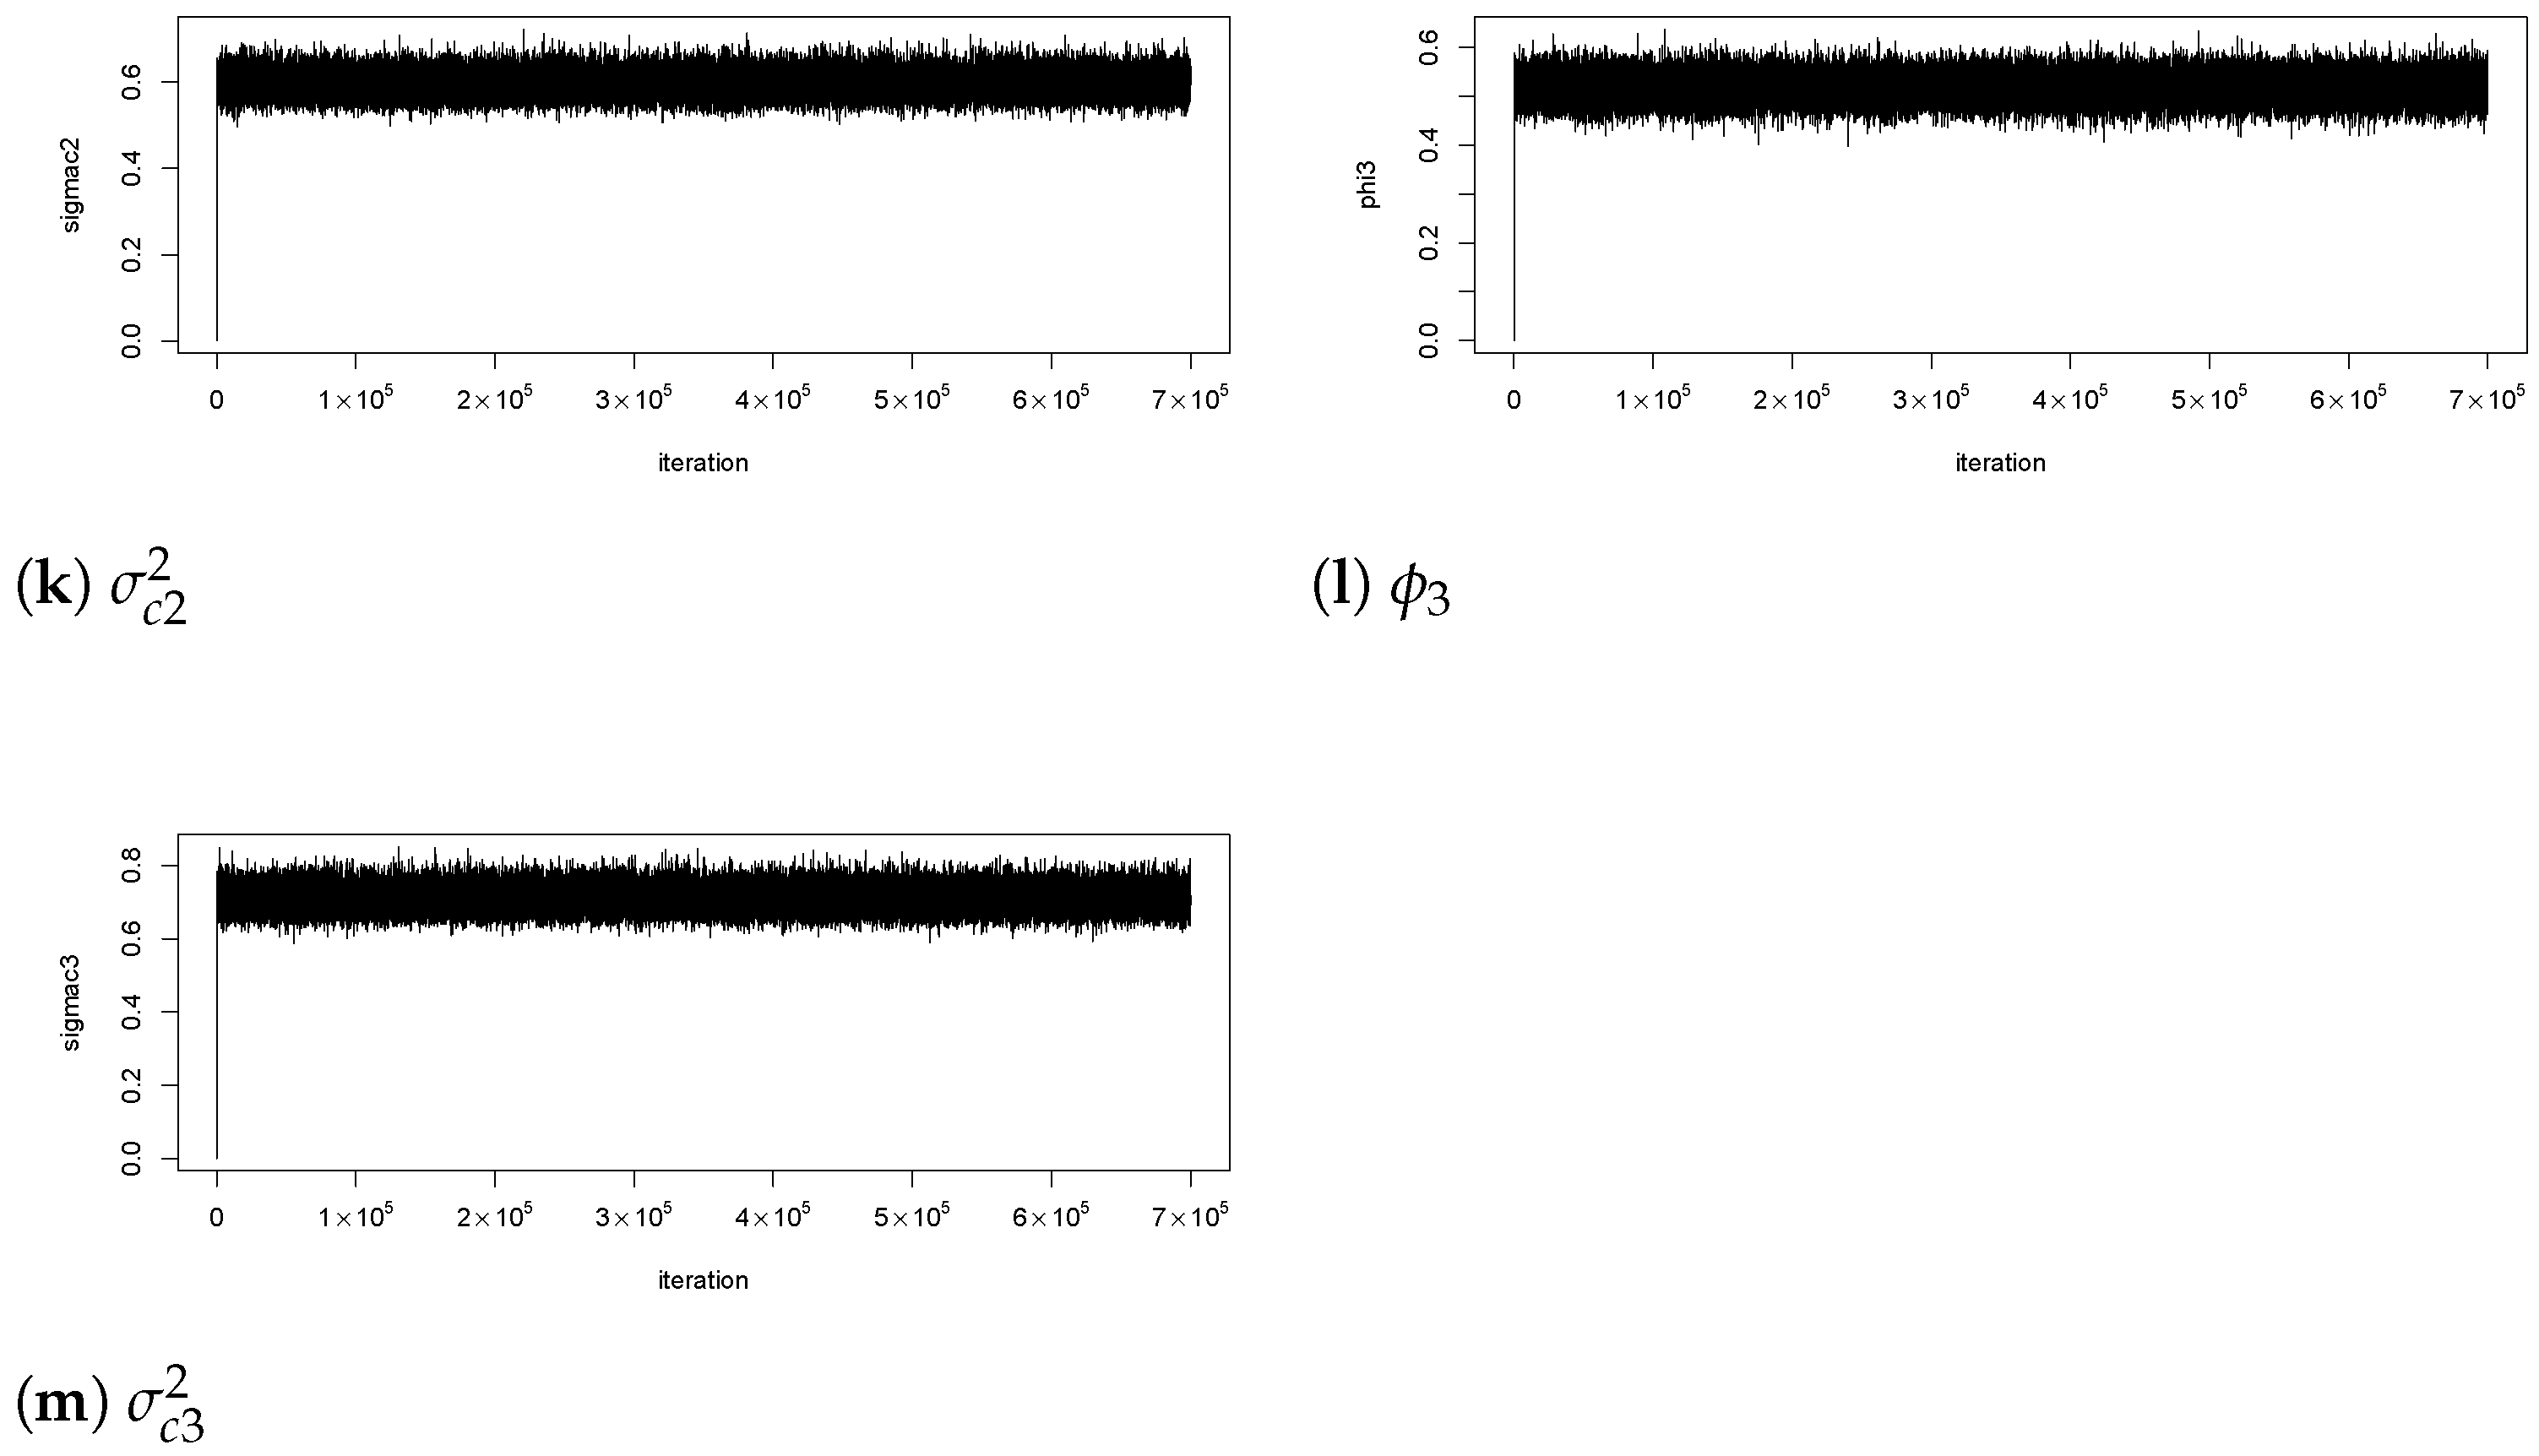
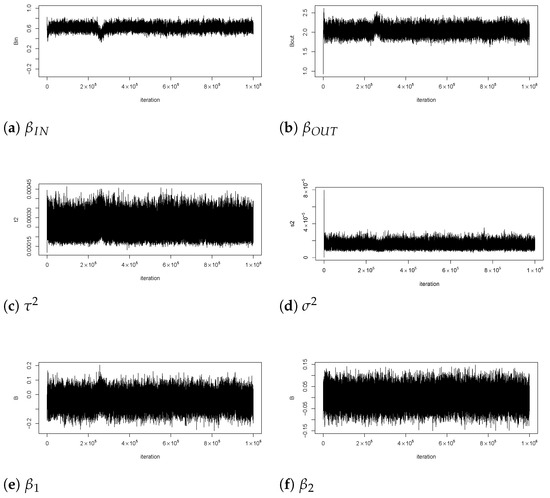
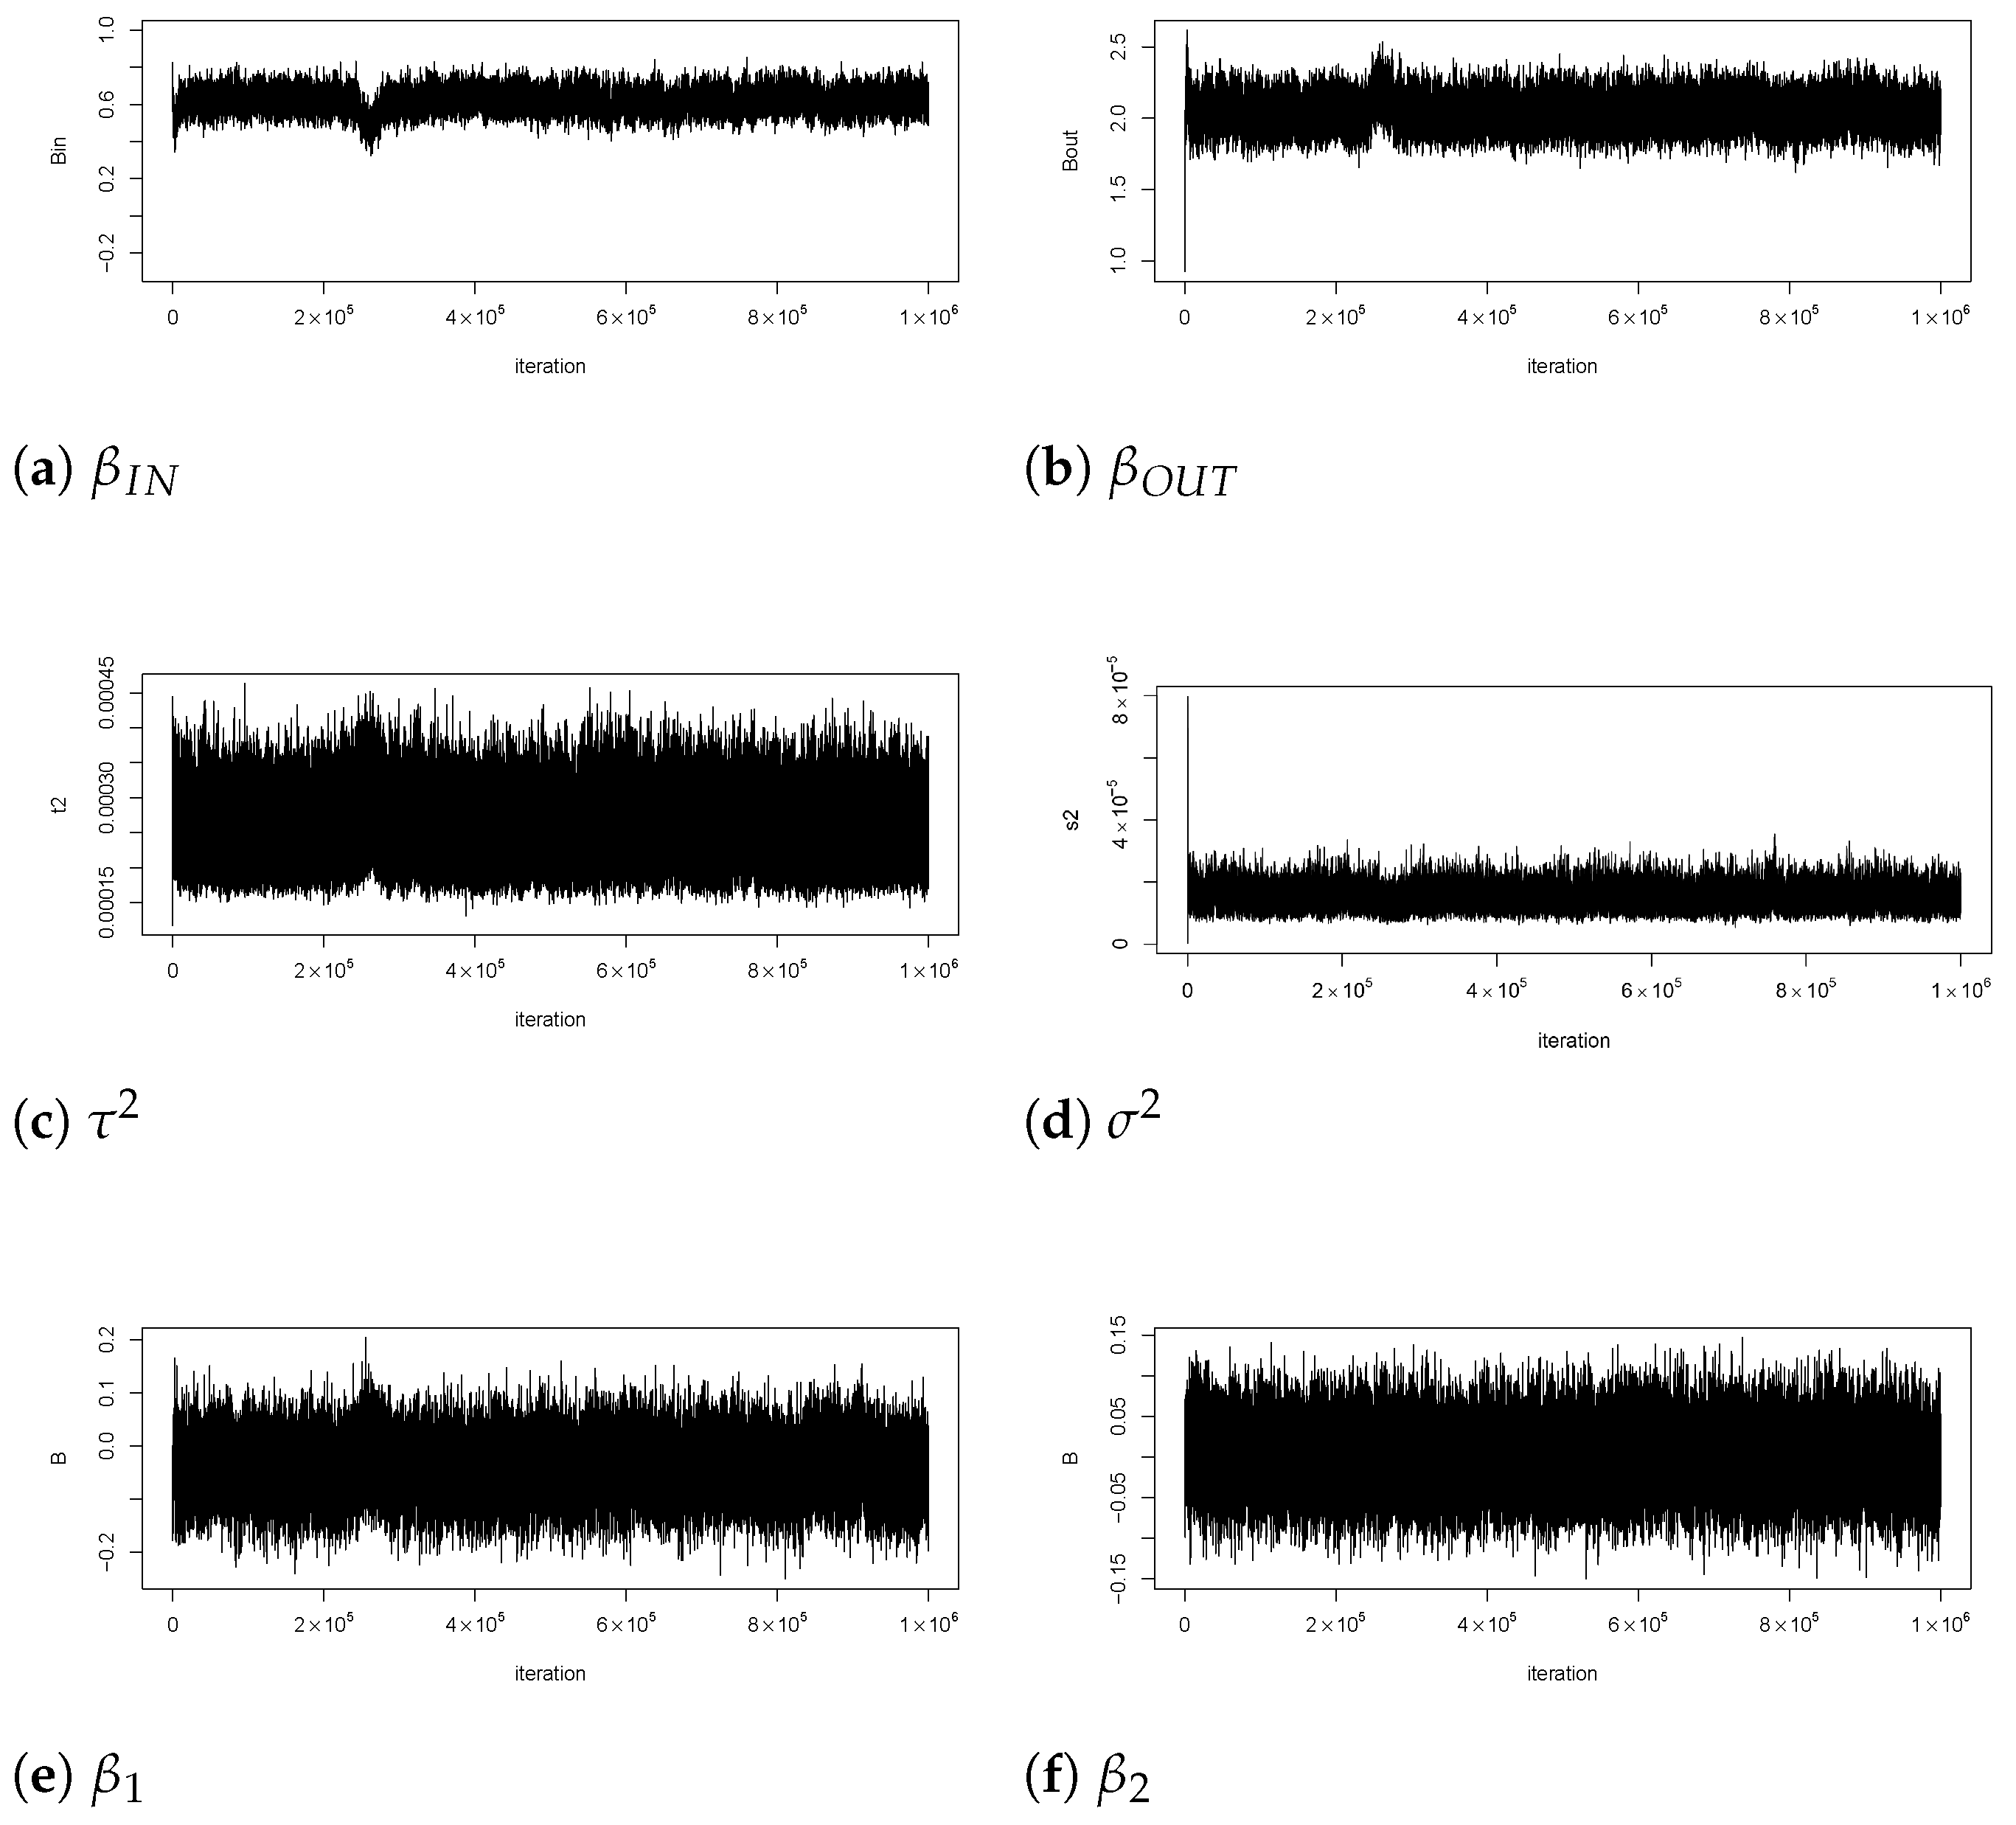
To estimate the extended DLSM parameters from Dataset 1, a total of 700,000 iterations was used, with a thinning parameter of 50. The first 200,000 iterations of the chain were removed in the burn-in stage. To assess convergence, both the MCMC trace plots and the Geweke test statistics (z-scores) [37] were used. The resulting Geweke z-scores are shown in Table 4 and are below 1.96 in absolute values for most parameters. For and , although the z-scores are larger, the MCMC trace plots show convergence, as shown in Figure 5a–m. Research with simulation studies has shown that the Geweke statistics tend to overestimate non-convergence in chains even in simulated data [38], and since the performance of the MCMC chains are consistent with ones in Sewell and Chen [13], it is believed that the Geweke statistics are acceptable in this case, and, therefore, it can be concluded that the chains have converged.
Table 4.
Mean estimates, corresponding 95% credible intervals, and Geweke z-scores for parameters of the actor-based covariate evolution model in Dataset 1.
Figure 5.
Trace plots of the MCMC samples in Dataset 1.
The means and 95% credible intervals of the estimated parameters for the extended DLSM with actor-based covariate evolution are also given in Table 4. For the covariate effects, it is observed that , suggesting that senders tend to form friendships with receivers who have higher social event attendance frequencies than themselves. Additionally, , indicating that senders prefer to befriend those who report lower happiness levels than themselves. For the covariate effect of pressure on network tie formation, , showing that senders tend to make friends with individuals who are feeling more pressured than themselves. As for the latent distance effects on network tie formation, it is observed that and . Thus, the senders being active in seeking friends is more important than the receivers being popular. In other words, sender identities are more important than receiver identities in friendship formation. In terms of the evolution process for latent positions, the small values show that the movements of latent positions from time point to time point are small as well. The covariate autoregressive effect parameters () for all three covariates are below 1.0, suggesting that the covariate evolution processes are stable and the change is not large.
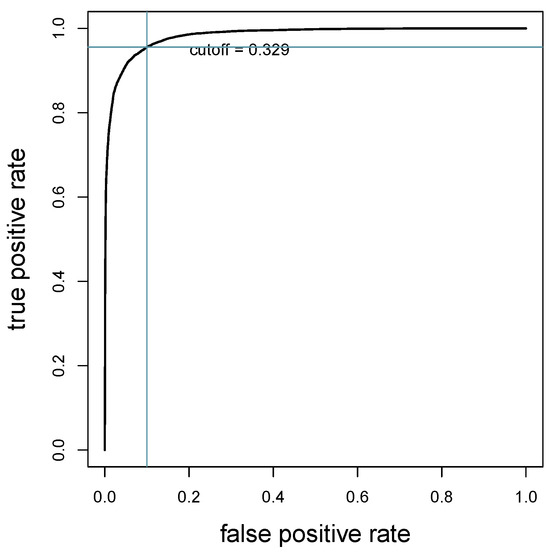
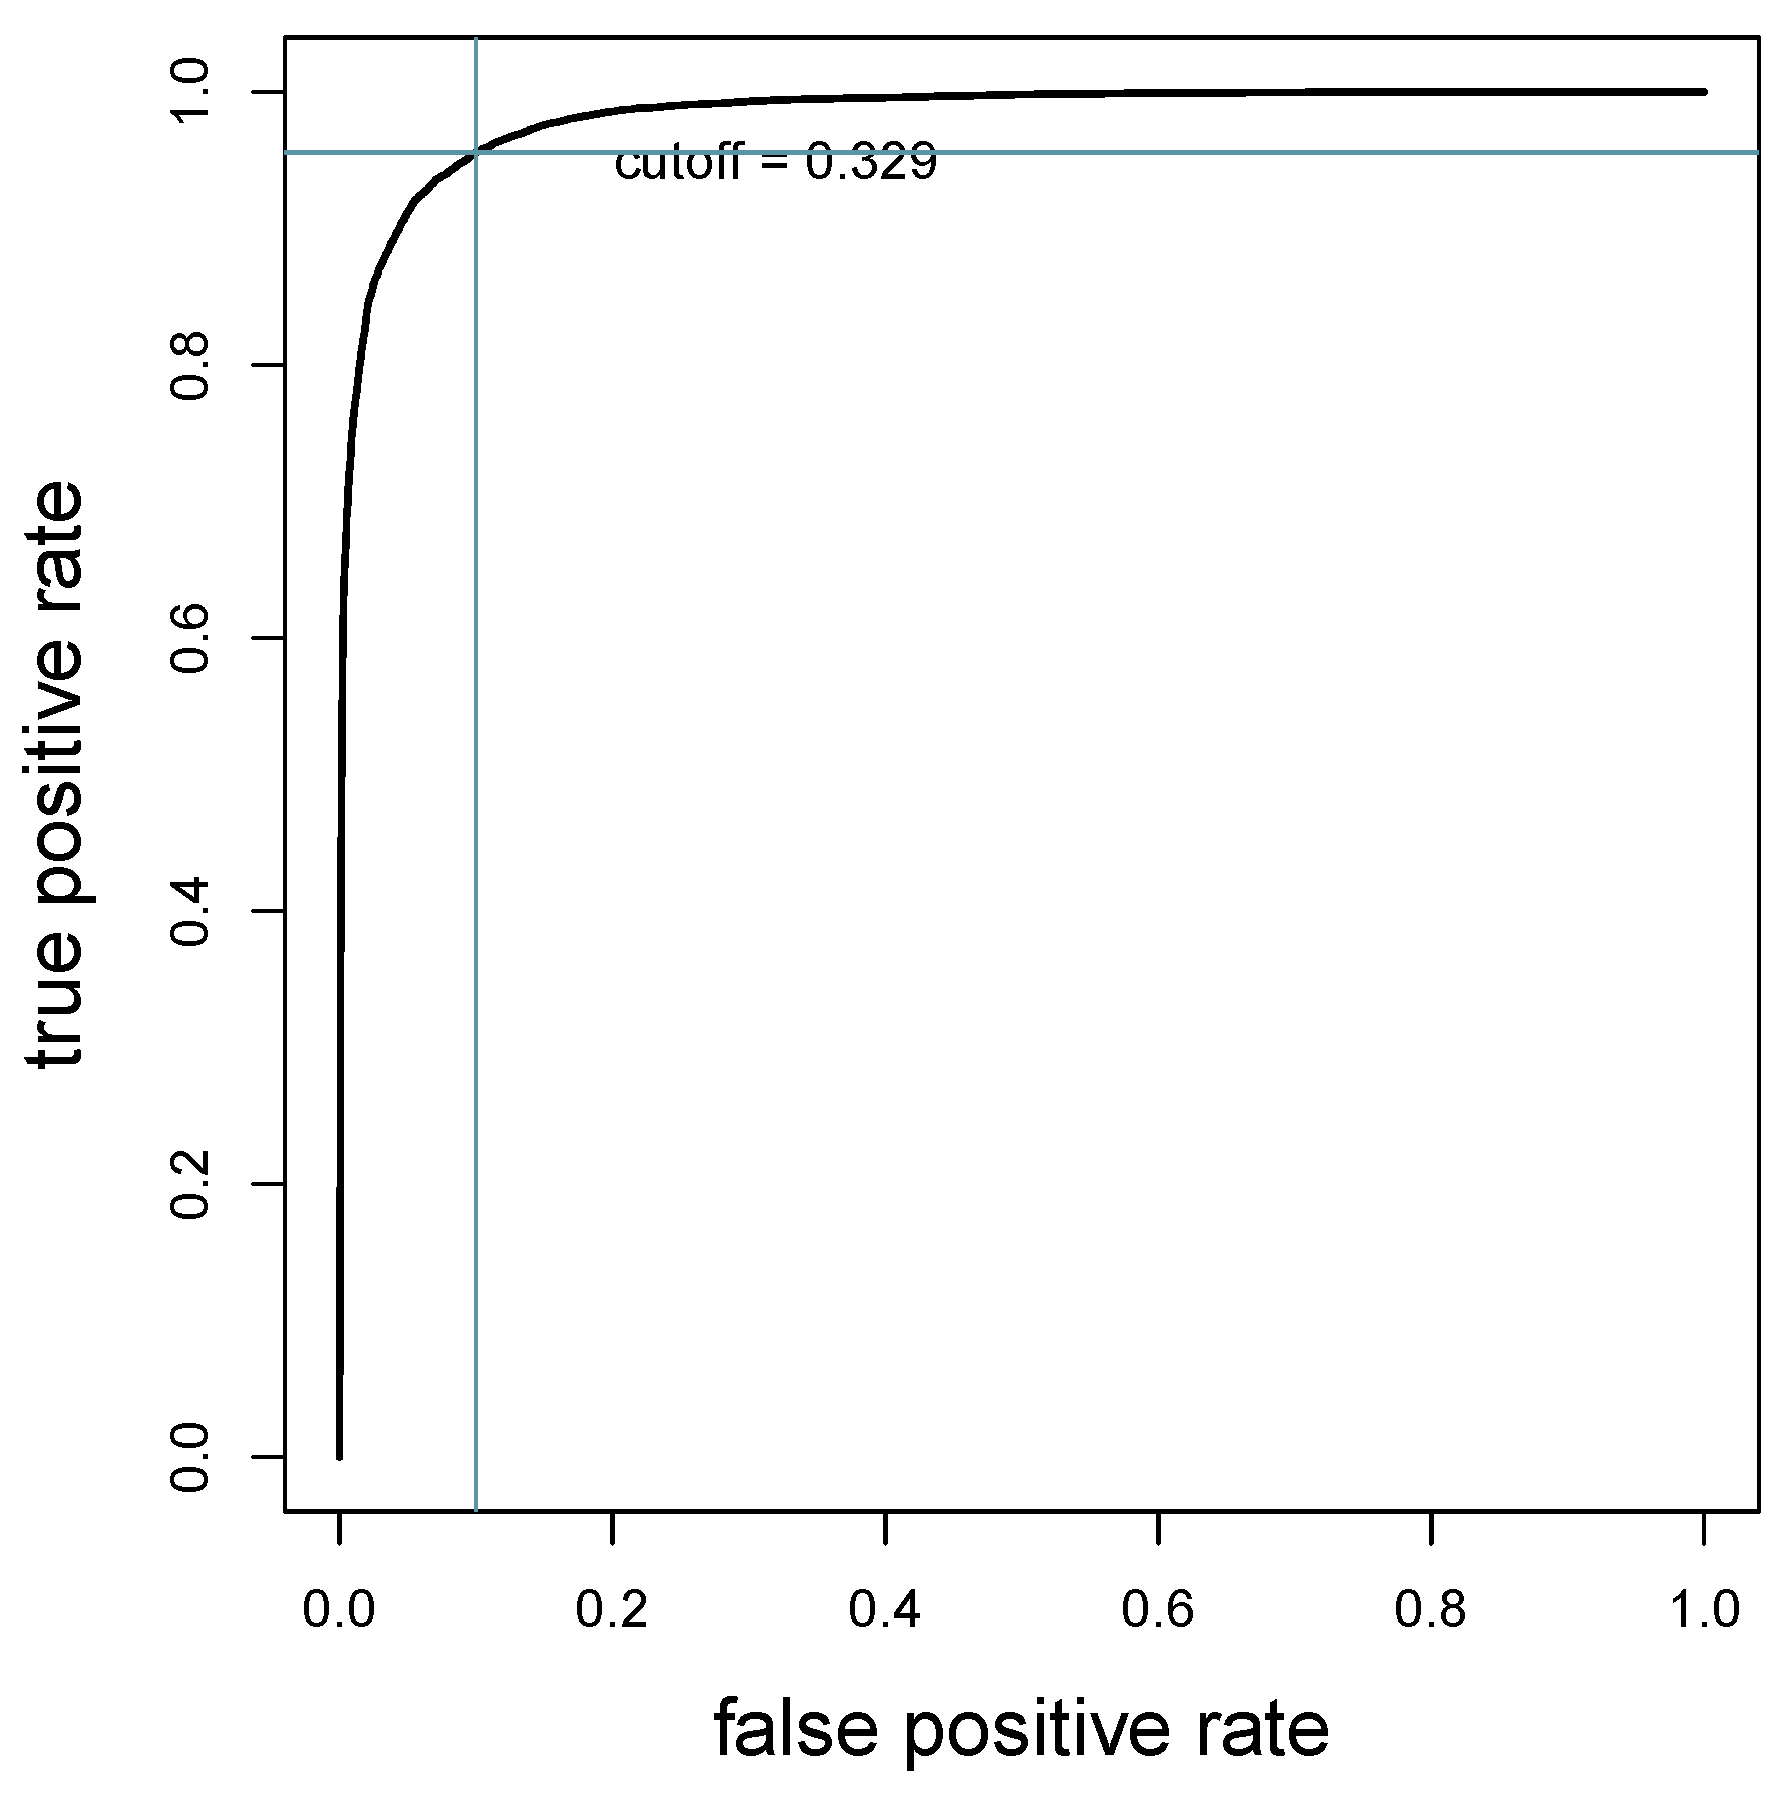
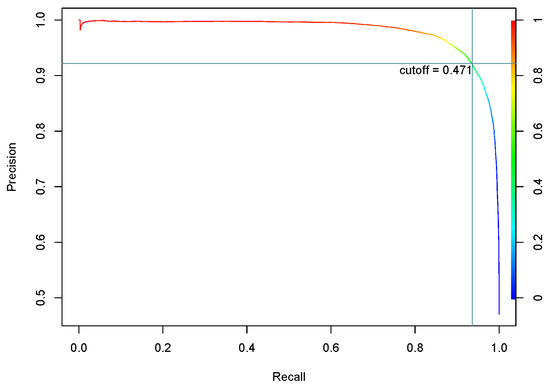
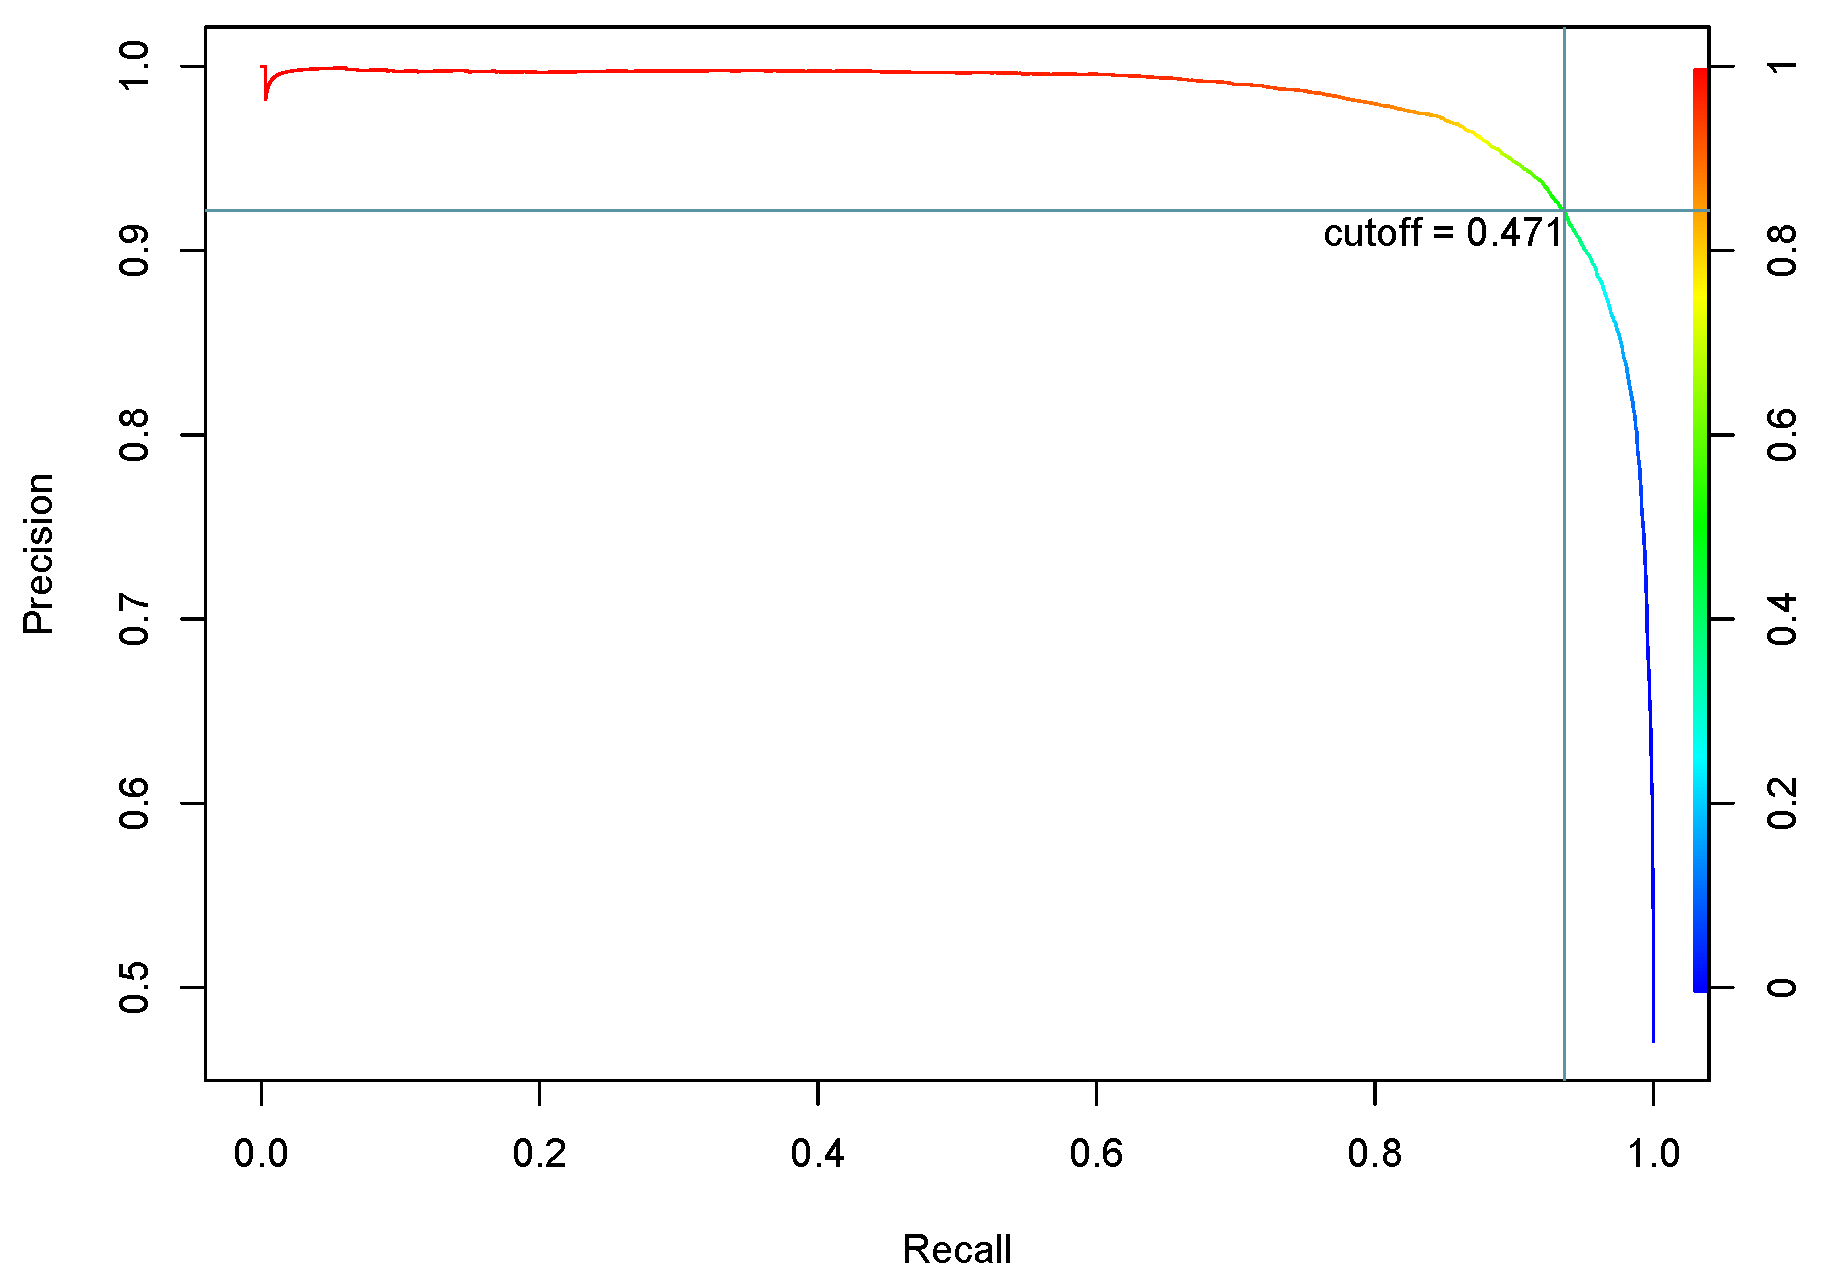
The AUC for this model is 0.983, which is desirable, and the ROC curve in Figure 6 shows that the best prediction performance of the model is achieved when using 0.329 as the cutoff for present or absent friendship. The false positive rate and true positive rate associated with the cutoff are 0.100 and 0.956. The model without covariate effects has an AUC of 0.981. Compared to the model without covariates, adding covariates in the current model only slightly improved AUC. The precision–recall curve of this model is shown in Figure 7. The model has both high precision and high recall around the top right corner, with values of 0.922 and 0.936 at a threshold of 0.471. This means that, at this threshold, the model not only ensures that most predicted positive edges correspond to true ties (high precision), but also successfully recovers the majority of the true edges in the network (high recall), indicating strong overall discriminative performance.
Figure 6.
The ROC curve of the three covariate model for Dataset 1.
Figure 7.
The precision–recall curve of the three covariate model for Dataset 1.
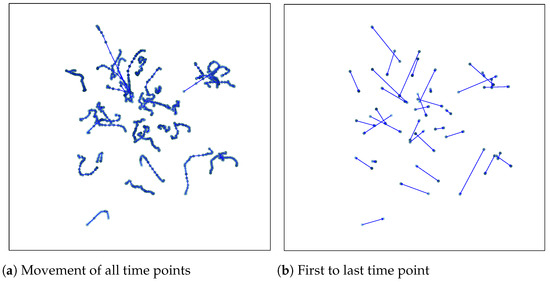
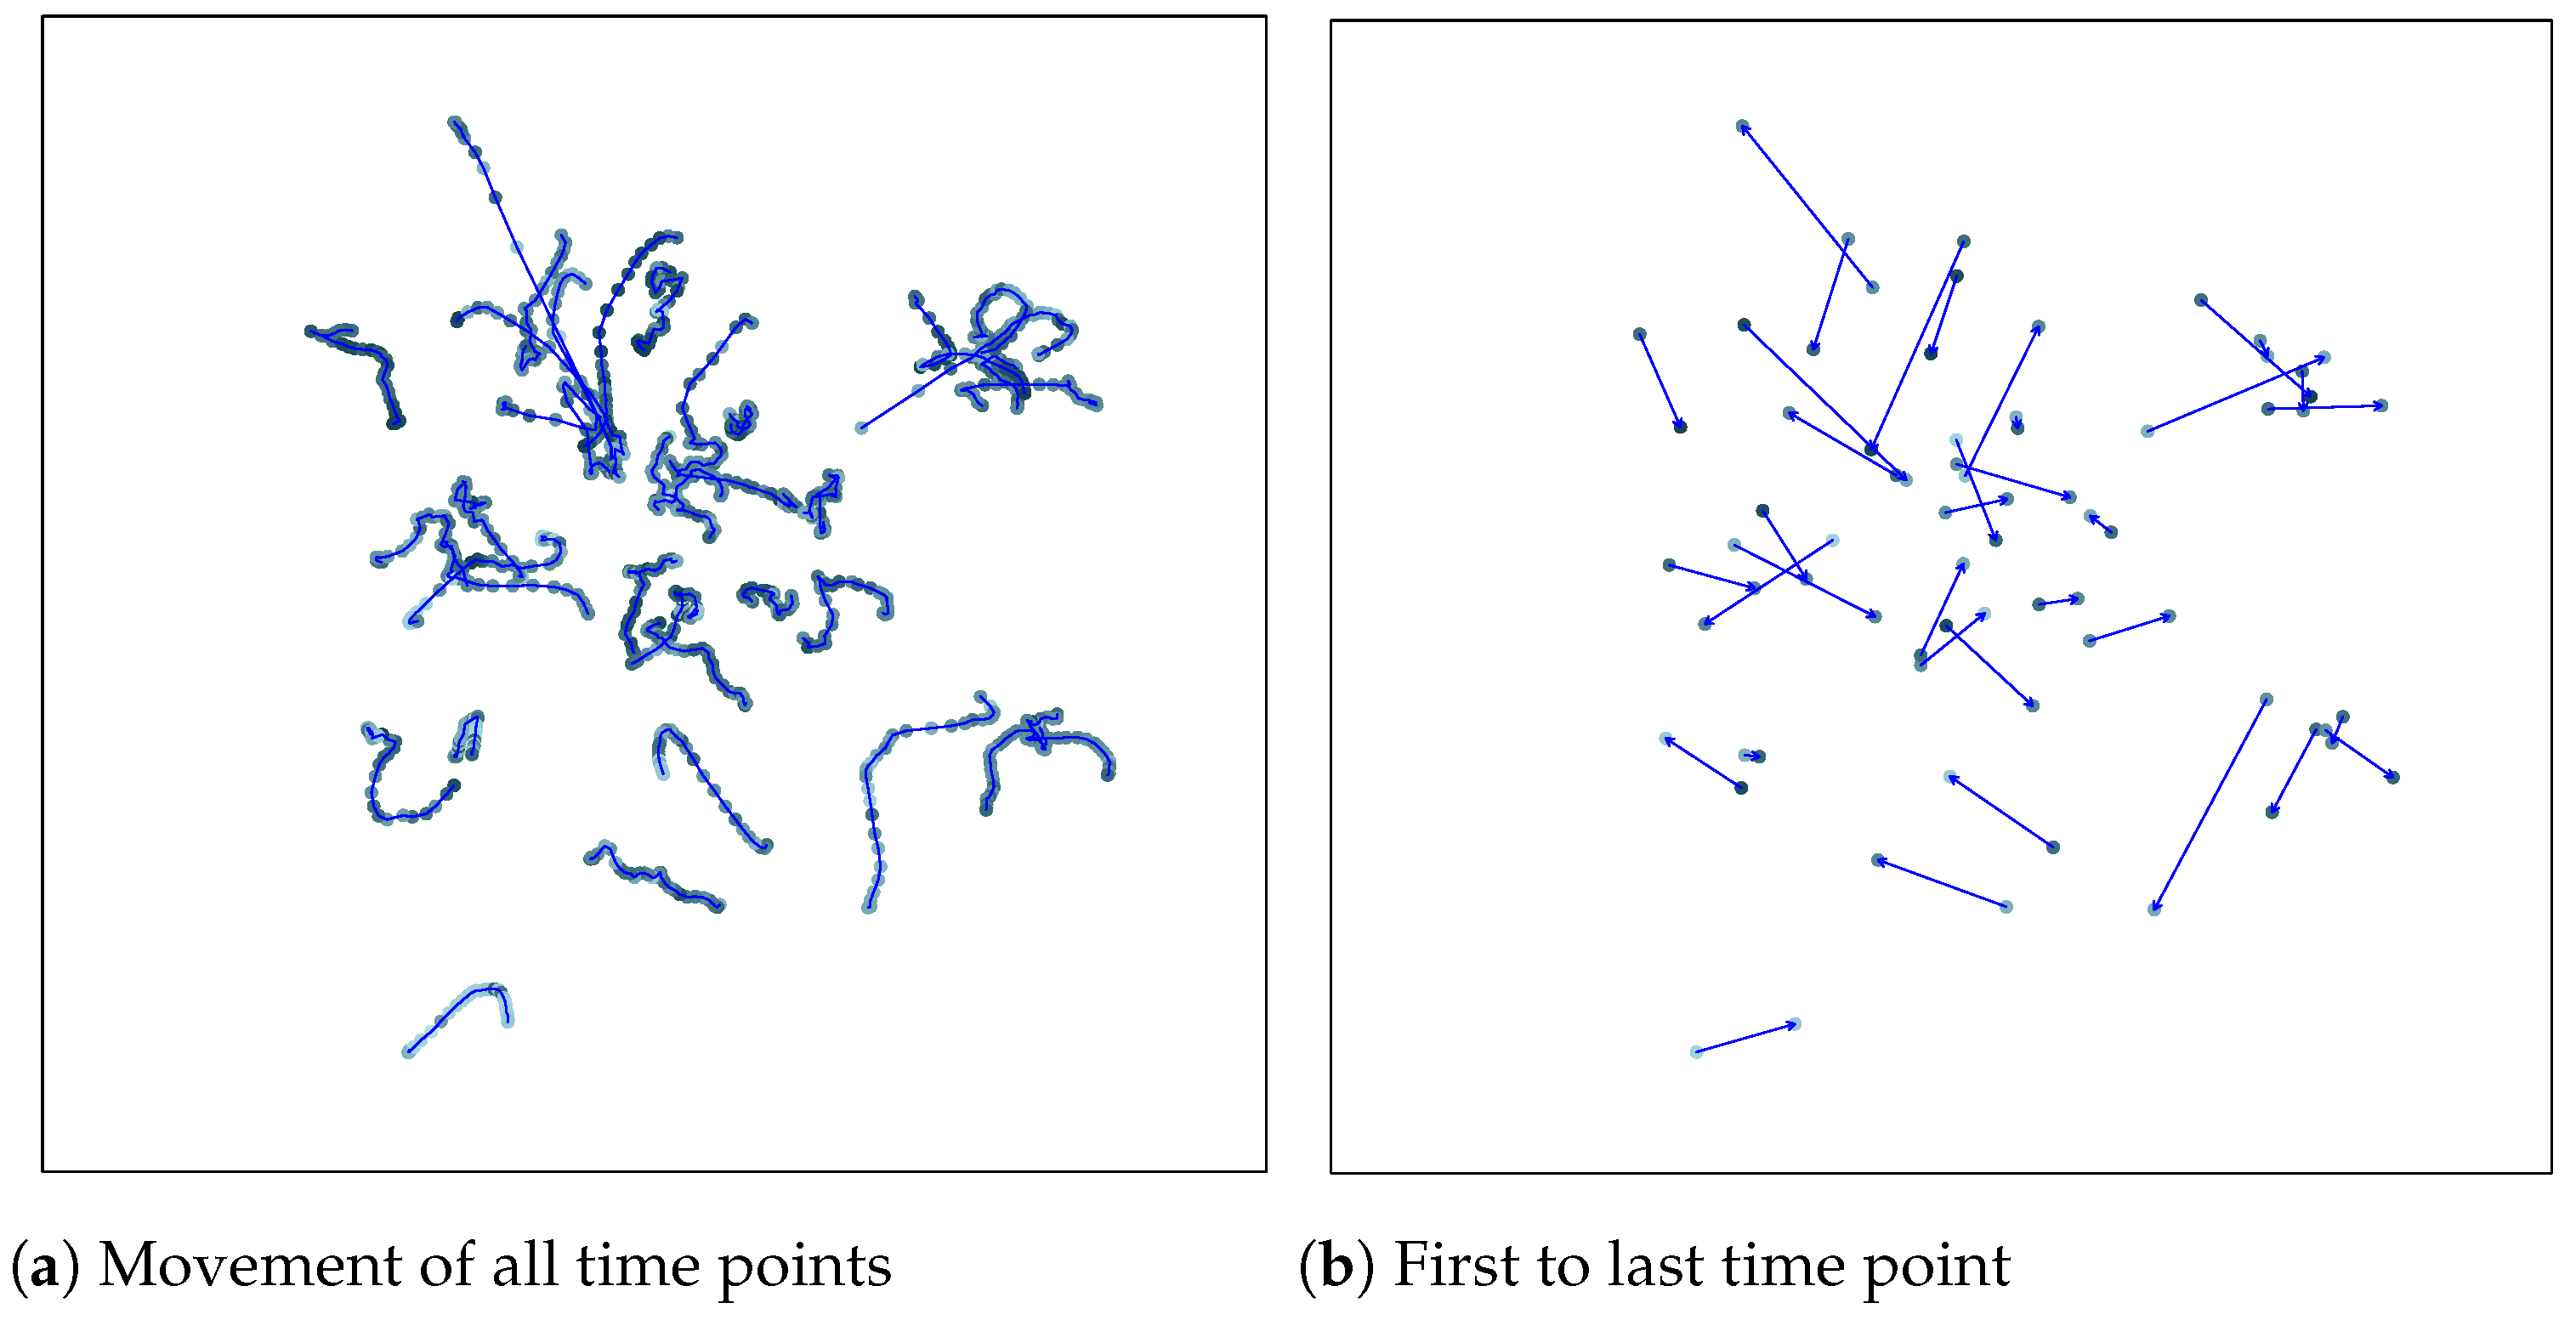
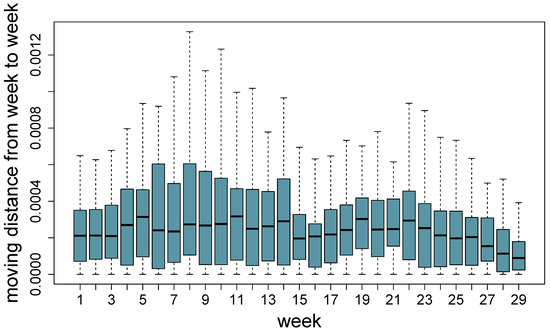
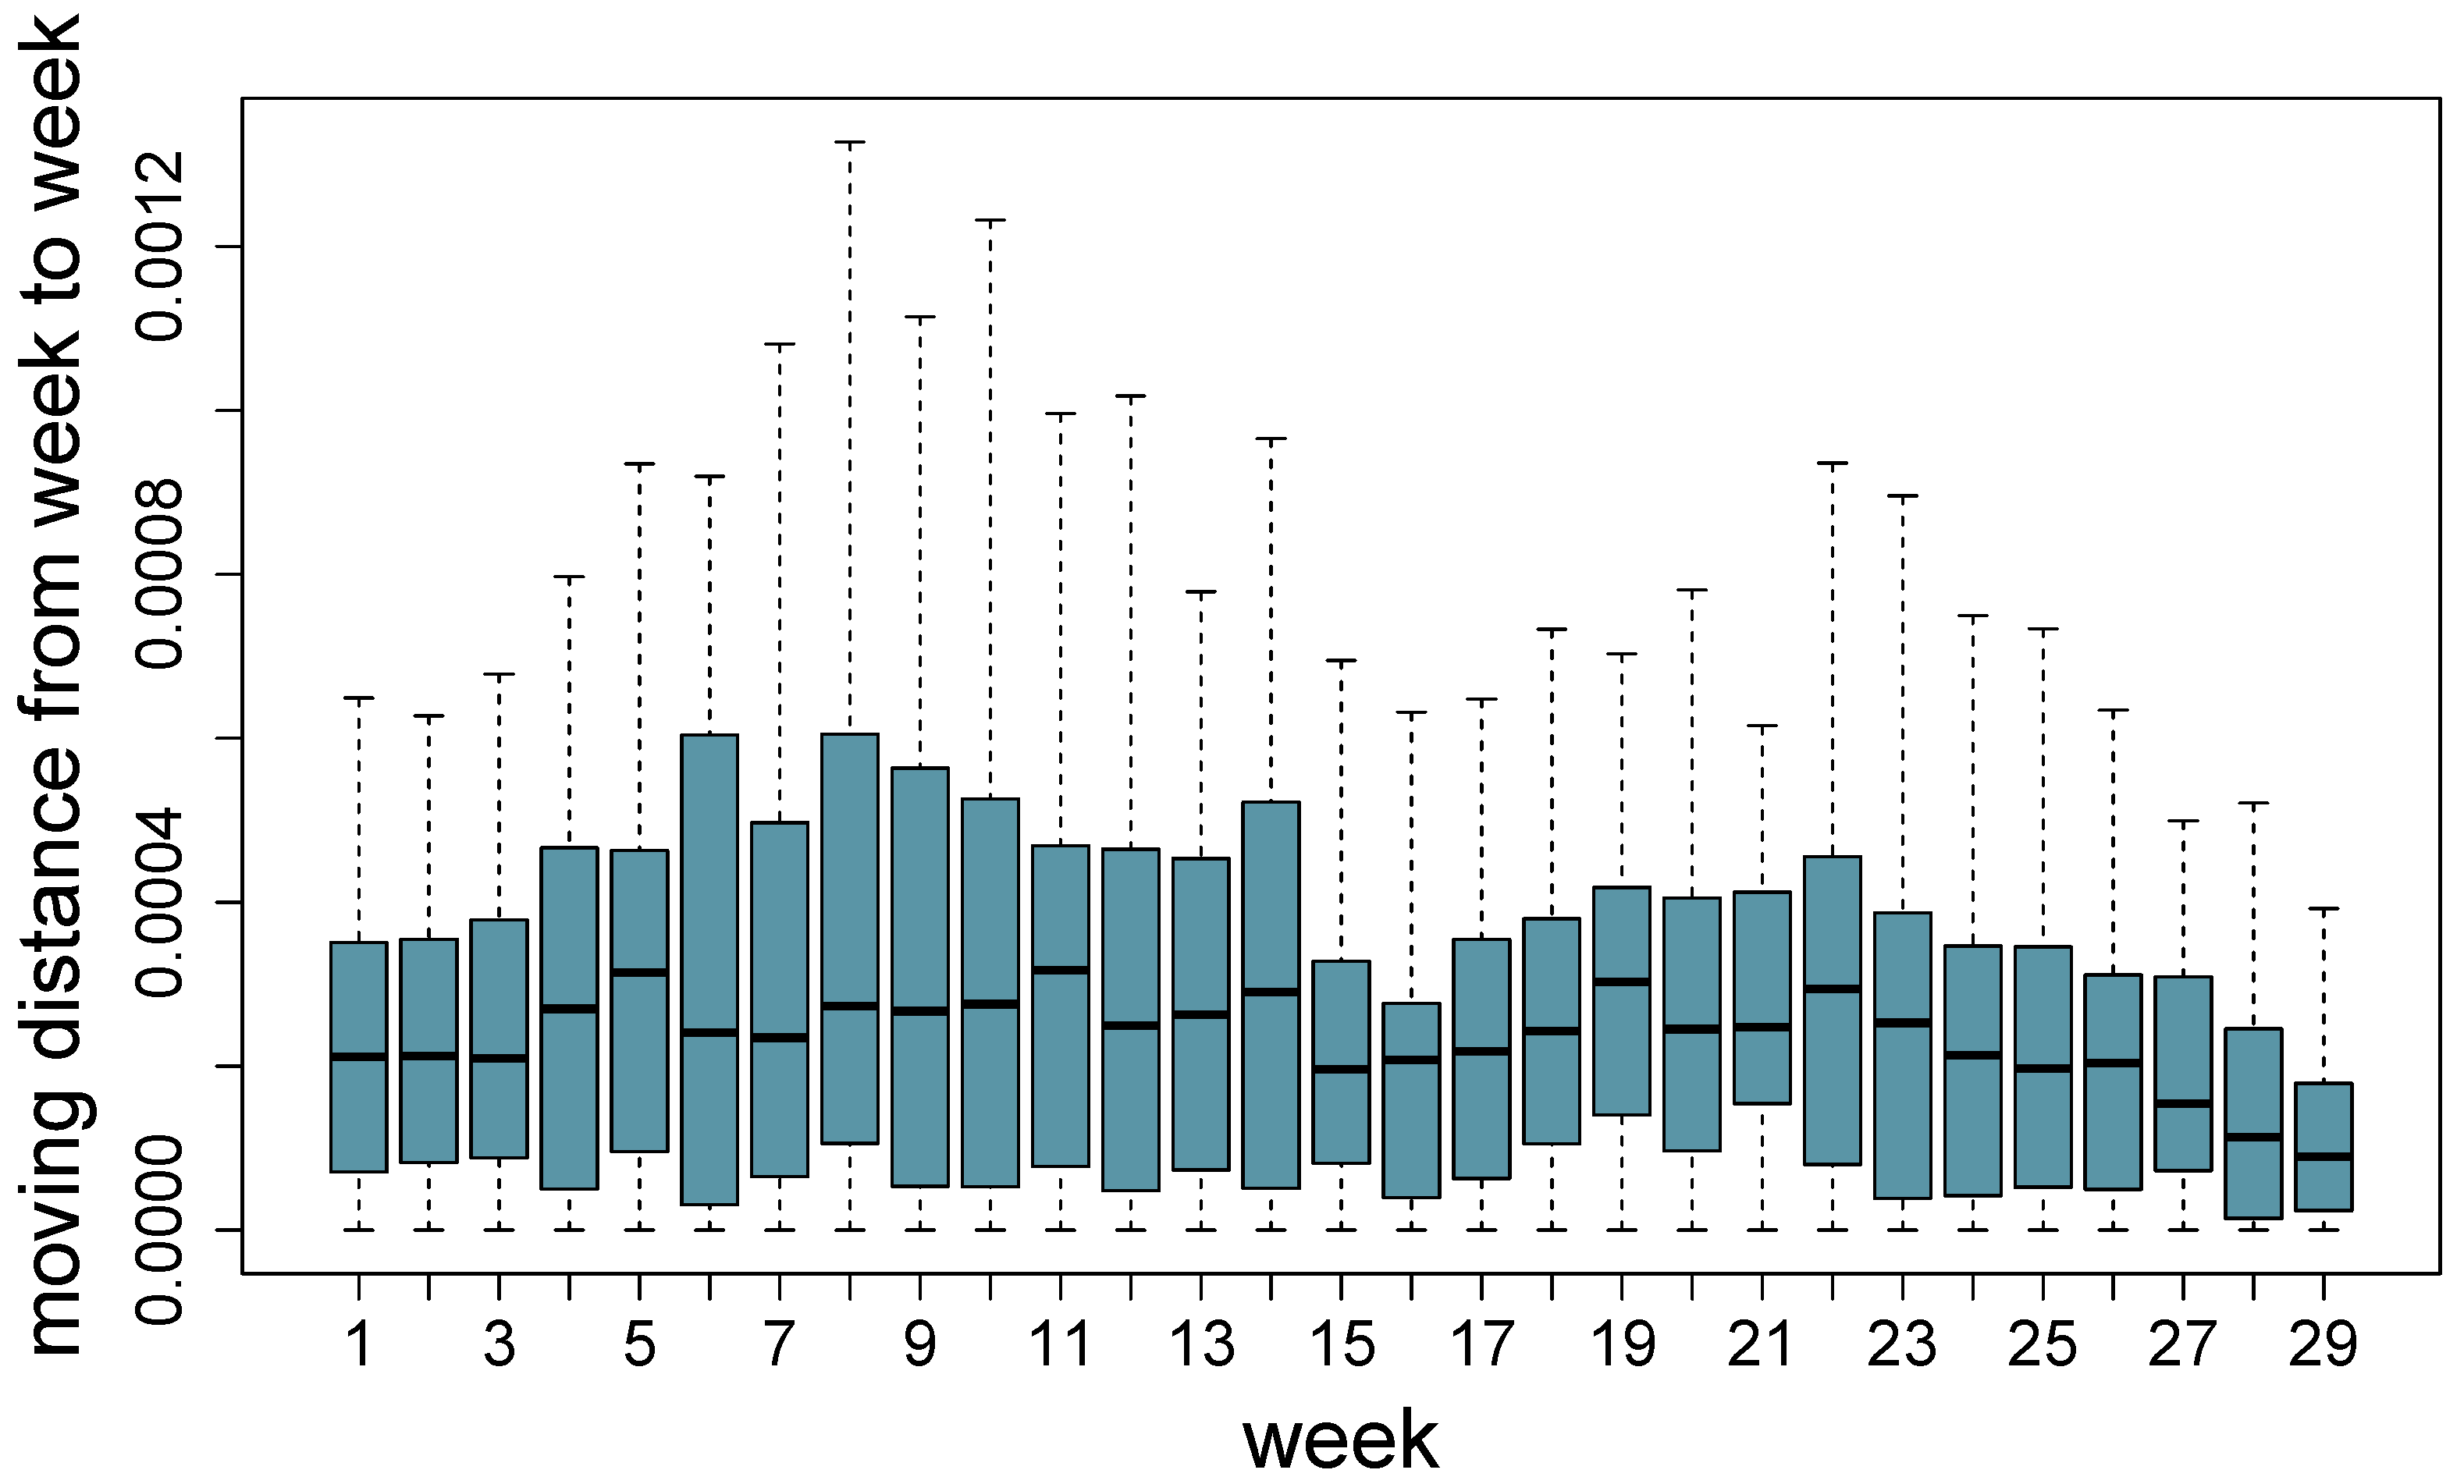
The posterior means of the latent position movement trends across time points for each individual in Dataset 1 are shown in Figure 8a,b. Figure 8a shows the moving trajectories of latent positions across all 30 weeks, whereas Figure 8b shows the initial and final latent positions. It can be shown from Figure 8a that each individual’s latent movement trajectory is slightly different, yet every individual moved to some extent across the 30-week time span. There are individuals with quite erratic latent position movements in the center part of Figure 8a, whereas individuals at the bottom of this figure tend to have smoother movements. In both cases, individuals tend to stay close within specific local regions of the latent space, suggesting relatively stable relationships across time. Aligning Figure 8a,b, it can also be concluded that measuring networks frequently could be meaningful since the trajectories are not always linear. It can also be observed that as latent positions change, the associated covariate, in this case, social event attendance, also fluctuates to different extents. The average latent position movement aggregated across individuals for each time point from an alternative perspective is shown in Figure 9. The average movement is slightly higher and more varied around week 10 and week 20, but the variations are quite small overall.
Figure 8.
Latent positions of students at selected time points, with the darker color dots indicating larger values of the covariate of social event attendance in Dataset 1.
Figure 9.
Mean latent moving distance in latent positions from week to week in Dataset 1.
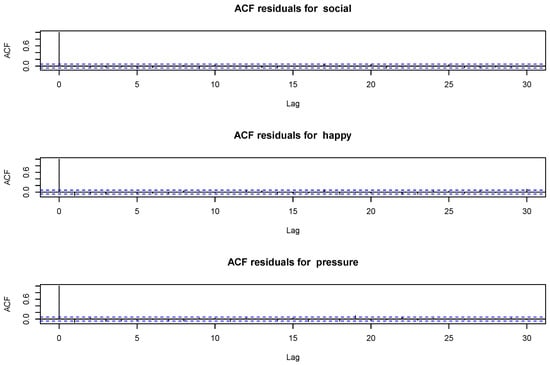
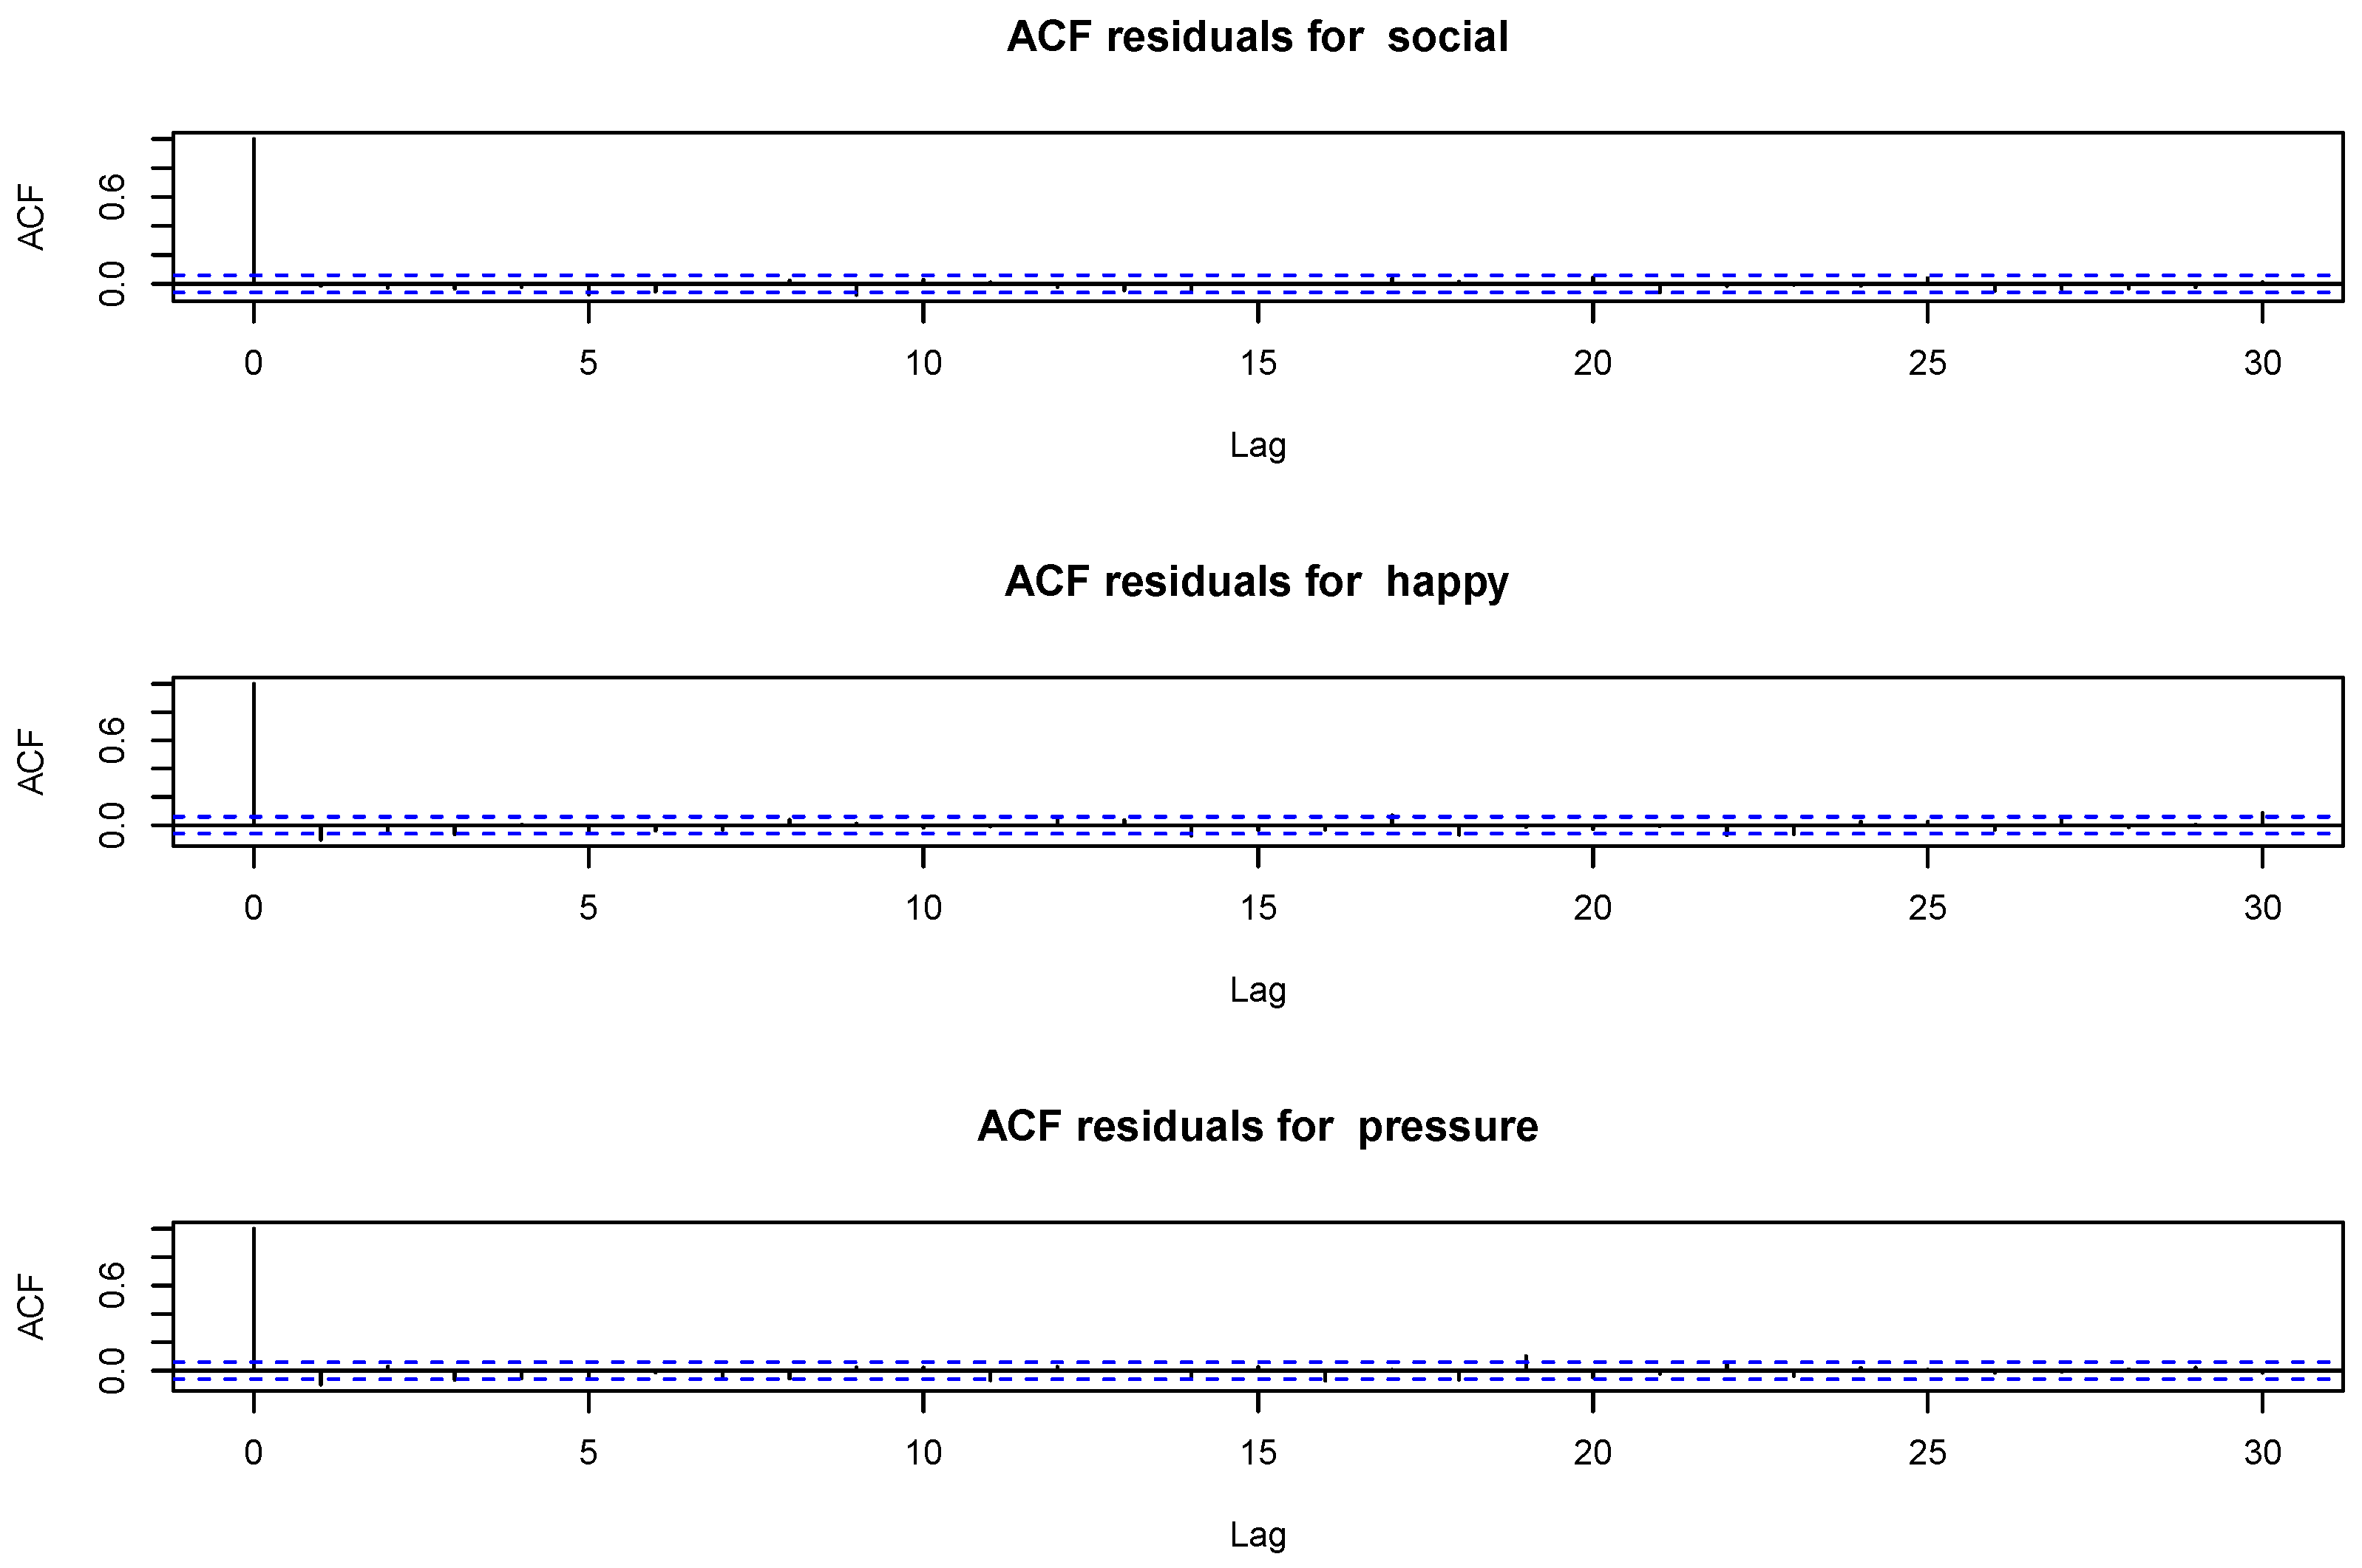
To assess whether the AR(1) process is appropriate for covariates in Dataset 1, autocorrelations of covariate residuals pooled across individuals after removing the AR(1) trends were plotted, as shown in Figure 10. Autocorrelations were all small, indicating that AR(1) is appropriate.
Figure 10.
Residual autocorrelation plots for covariates in Dataset 1. The blue horizontal lines indicate the 95% confidence limits under the null hypothesis of no autocorrelation.
3.3.2. Results of Dataset 2
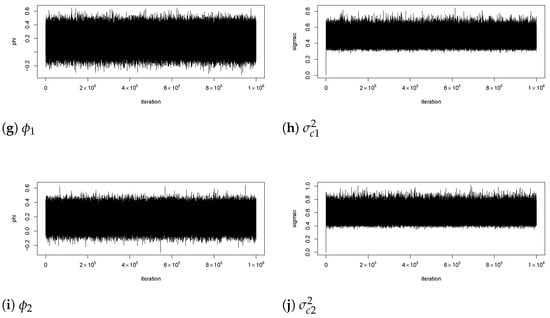
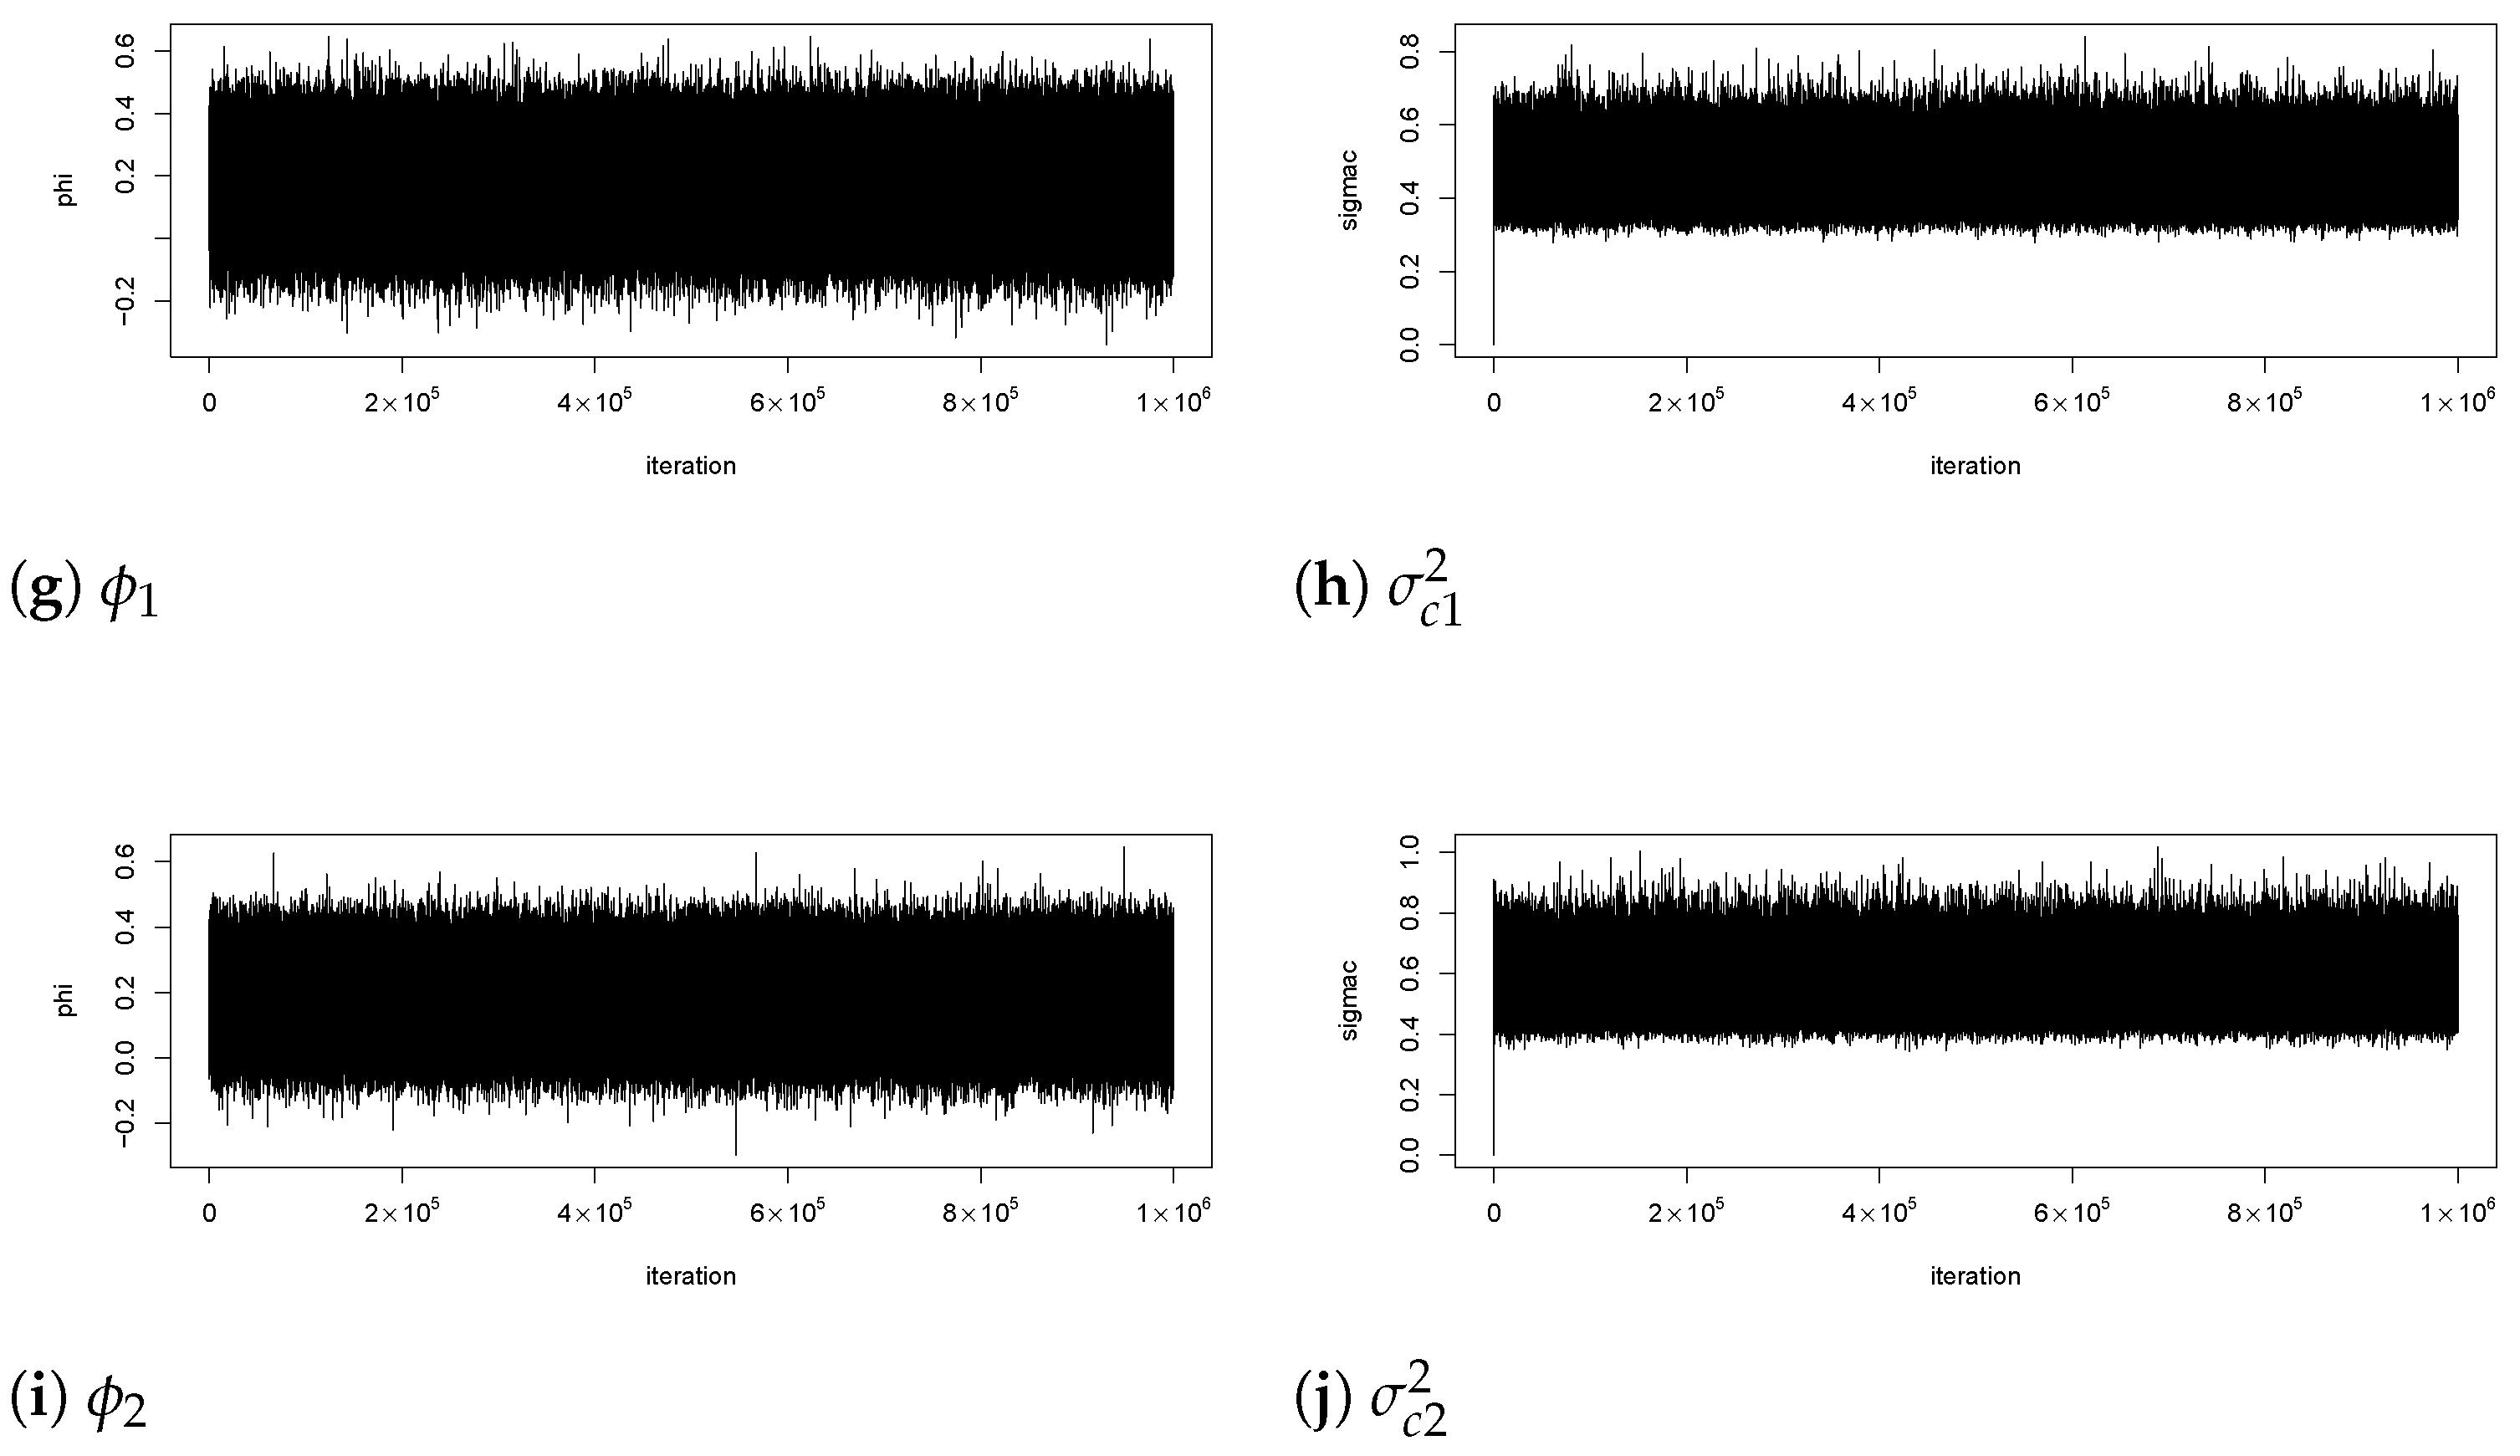
For estimating the parameters of the extended DLSM in Dataset 2, one chain with 1,000,000 iterations is used, with 300,000 iterations removed as burn-in after inspecting the MCMC plots. A thinning parameter of 10 is used. After fitting the extended DLSM to the dataset, the convergence of parameters is assessed with Geweke statistics shown in Table 5, which are mostly satisfactory except that the z-scores for and have slightly larger values. After further checking the MCMC plots in Figure 11a–j, it can be concluded that the parameters have converged. The resulting means and credible intervals of parameters are also shown in Table 5. The 95% credible interval for parameters other than , and excludes 0. Focusing on the covariate effects, , suggesting that senders tend to make friends with receivers with higher loneliness levels than themselves; , suggesting that senders like to make friends with receivers with lower extroversion scores. Both covariate effects are really small. As for the latent distance effects, and are both positive with , indicating that the identities of senders are more important in friendship formation than receivers. The latent position movement parameters are again small for this dataset. For the covariate autoregressive effects, both loneliness and extroversion have stationary AR(1) processes with autoregressive coefficients smaller than 1.
Table 5.
Mean estimates, corresponding 95% credible intervals, and Geweke z-scores for parameters in Dataset 2.
Figure 11.
Trace plots of the MCMC samples in Dataset 2.
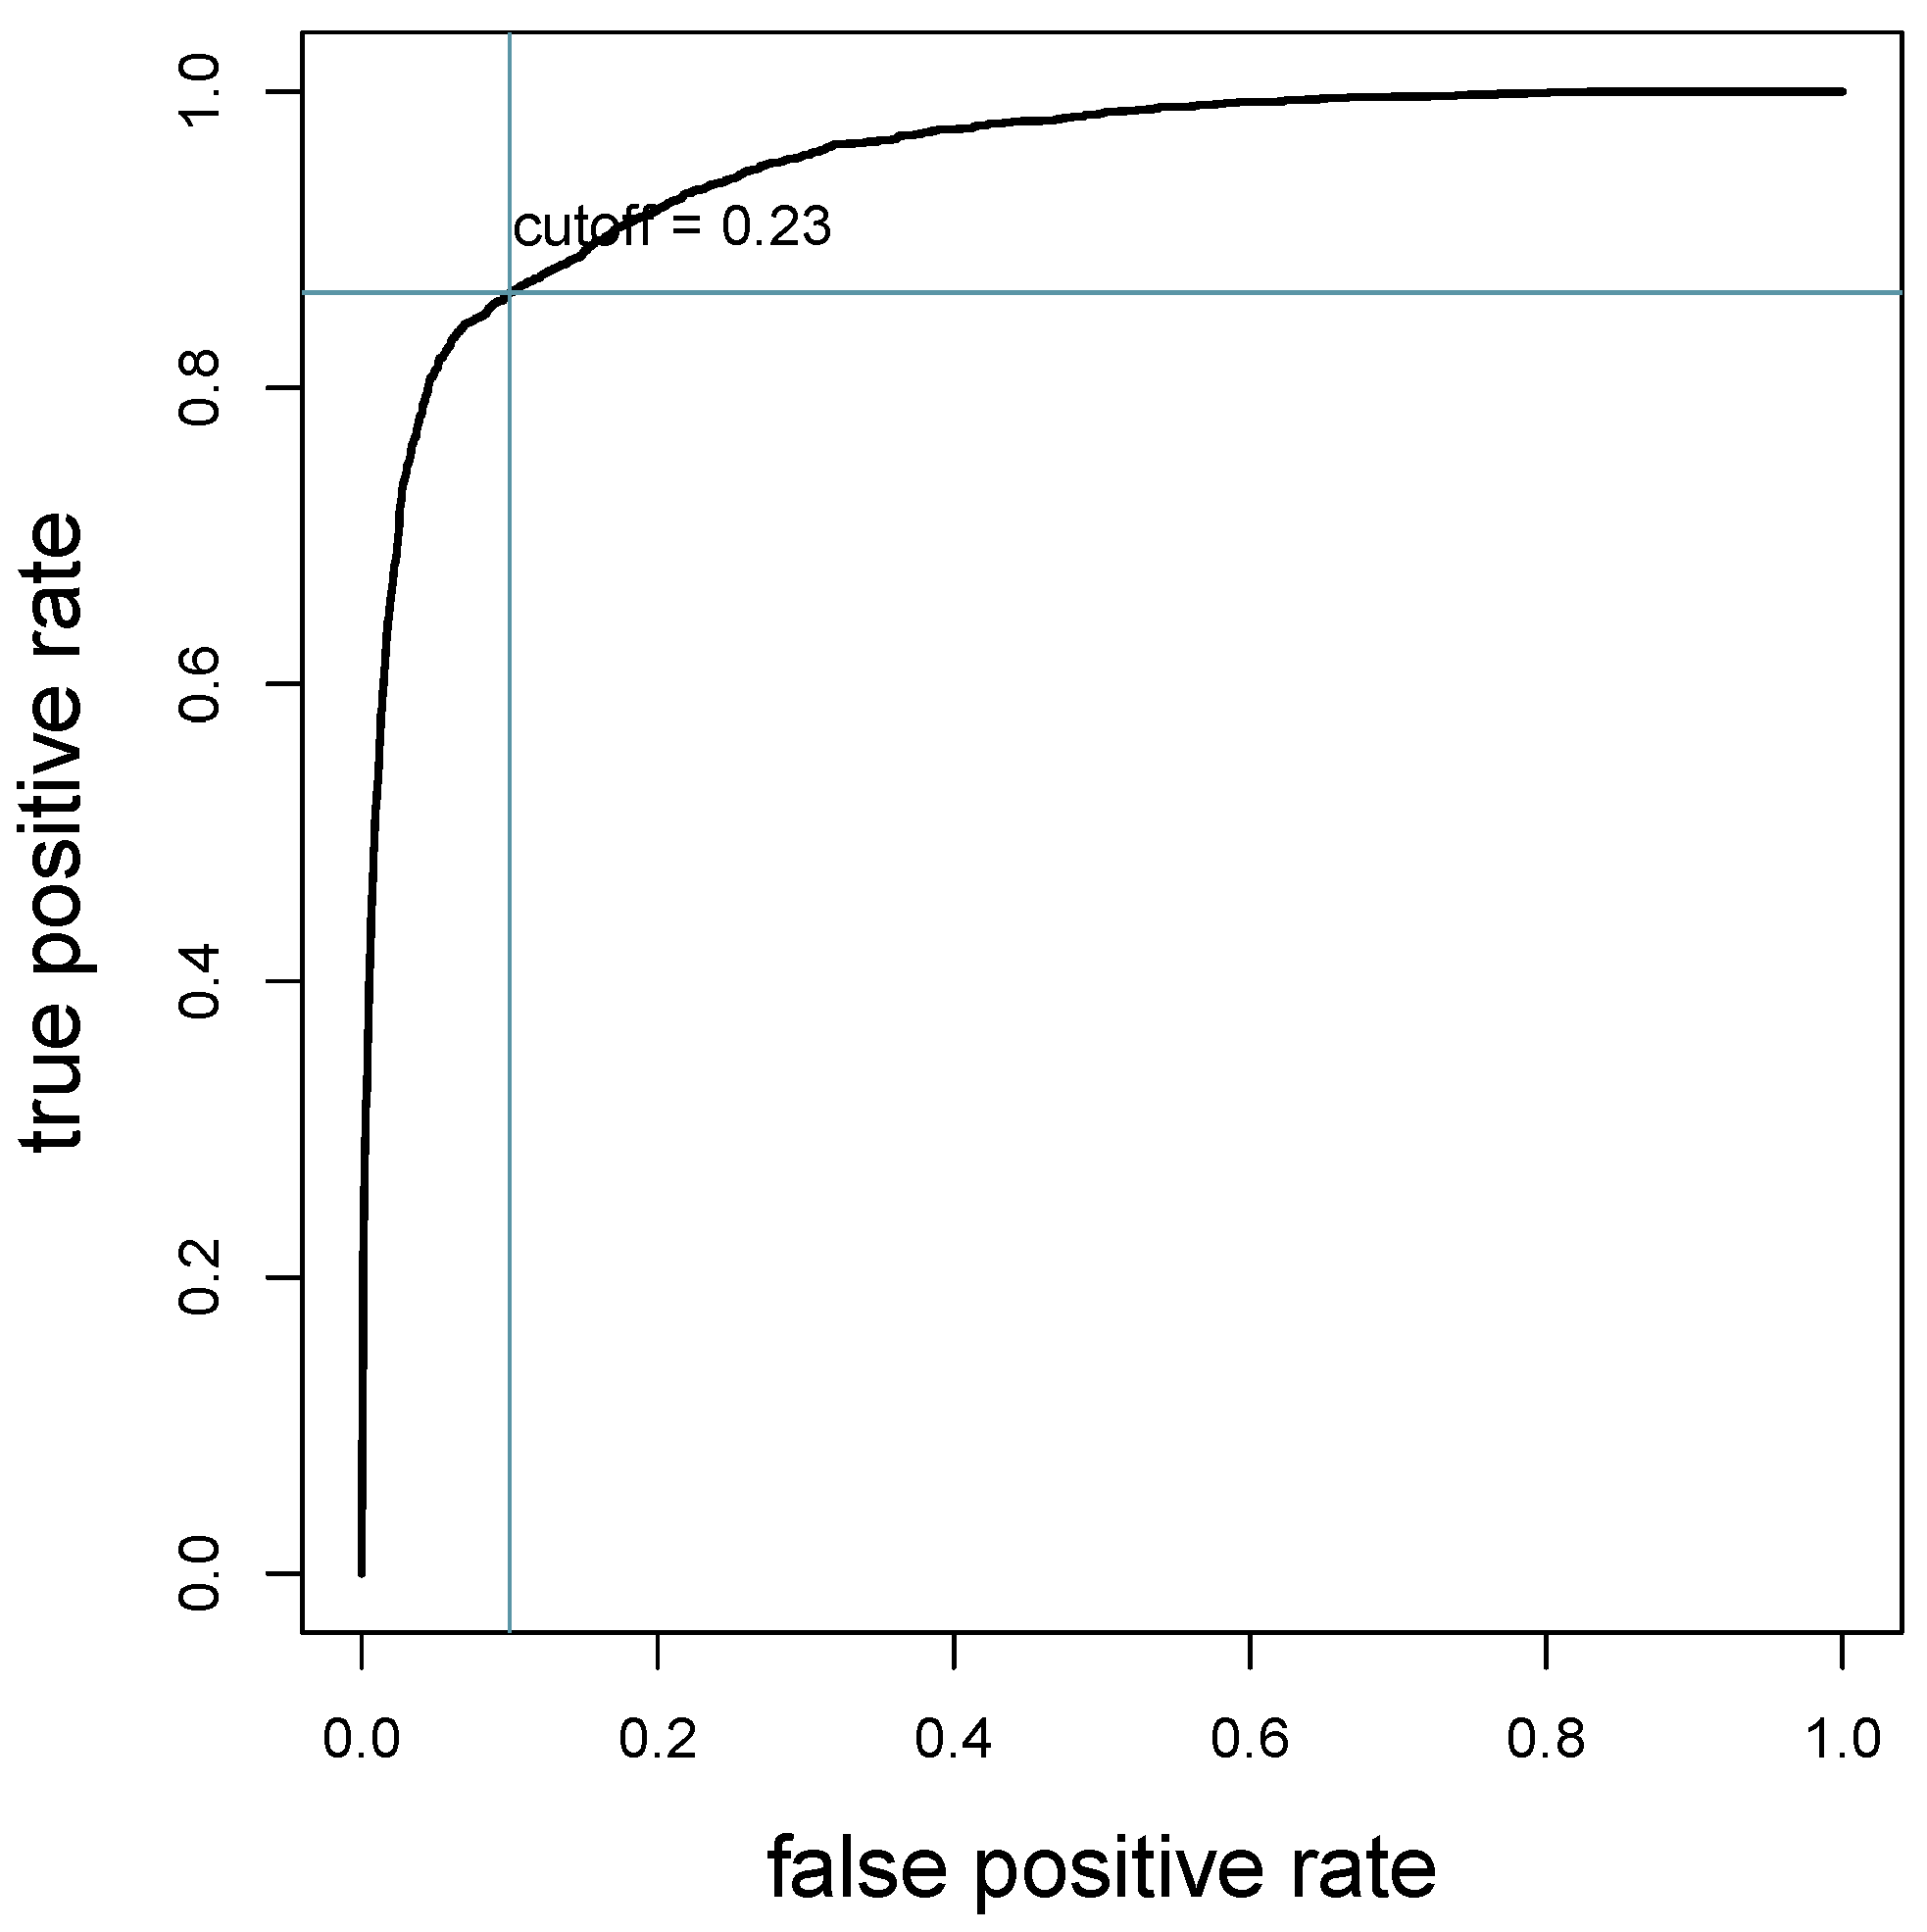
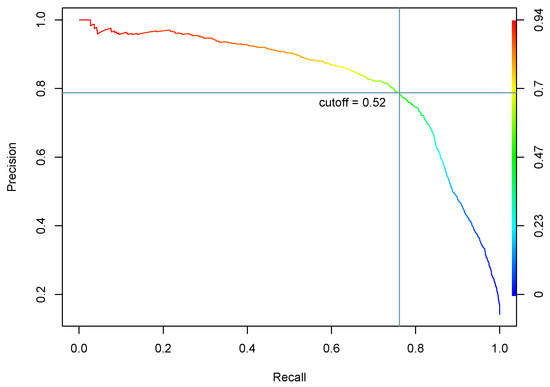
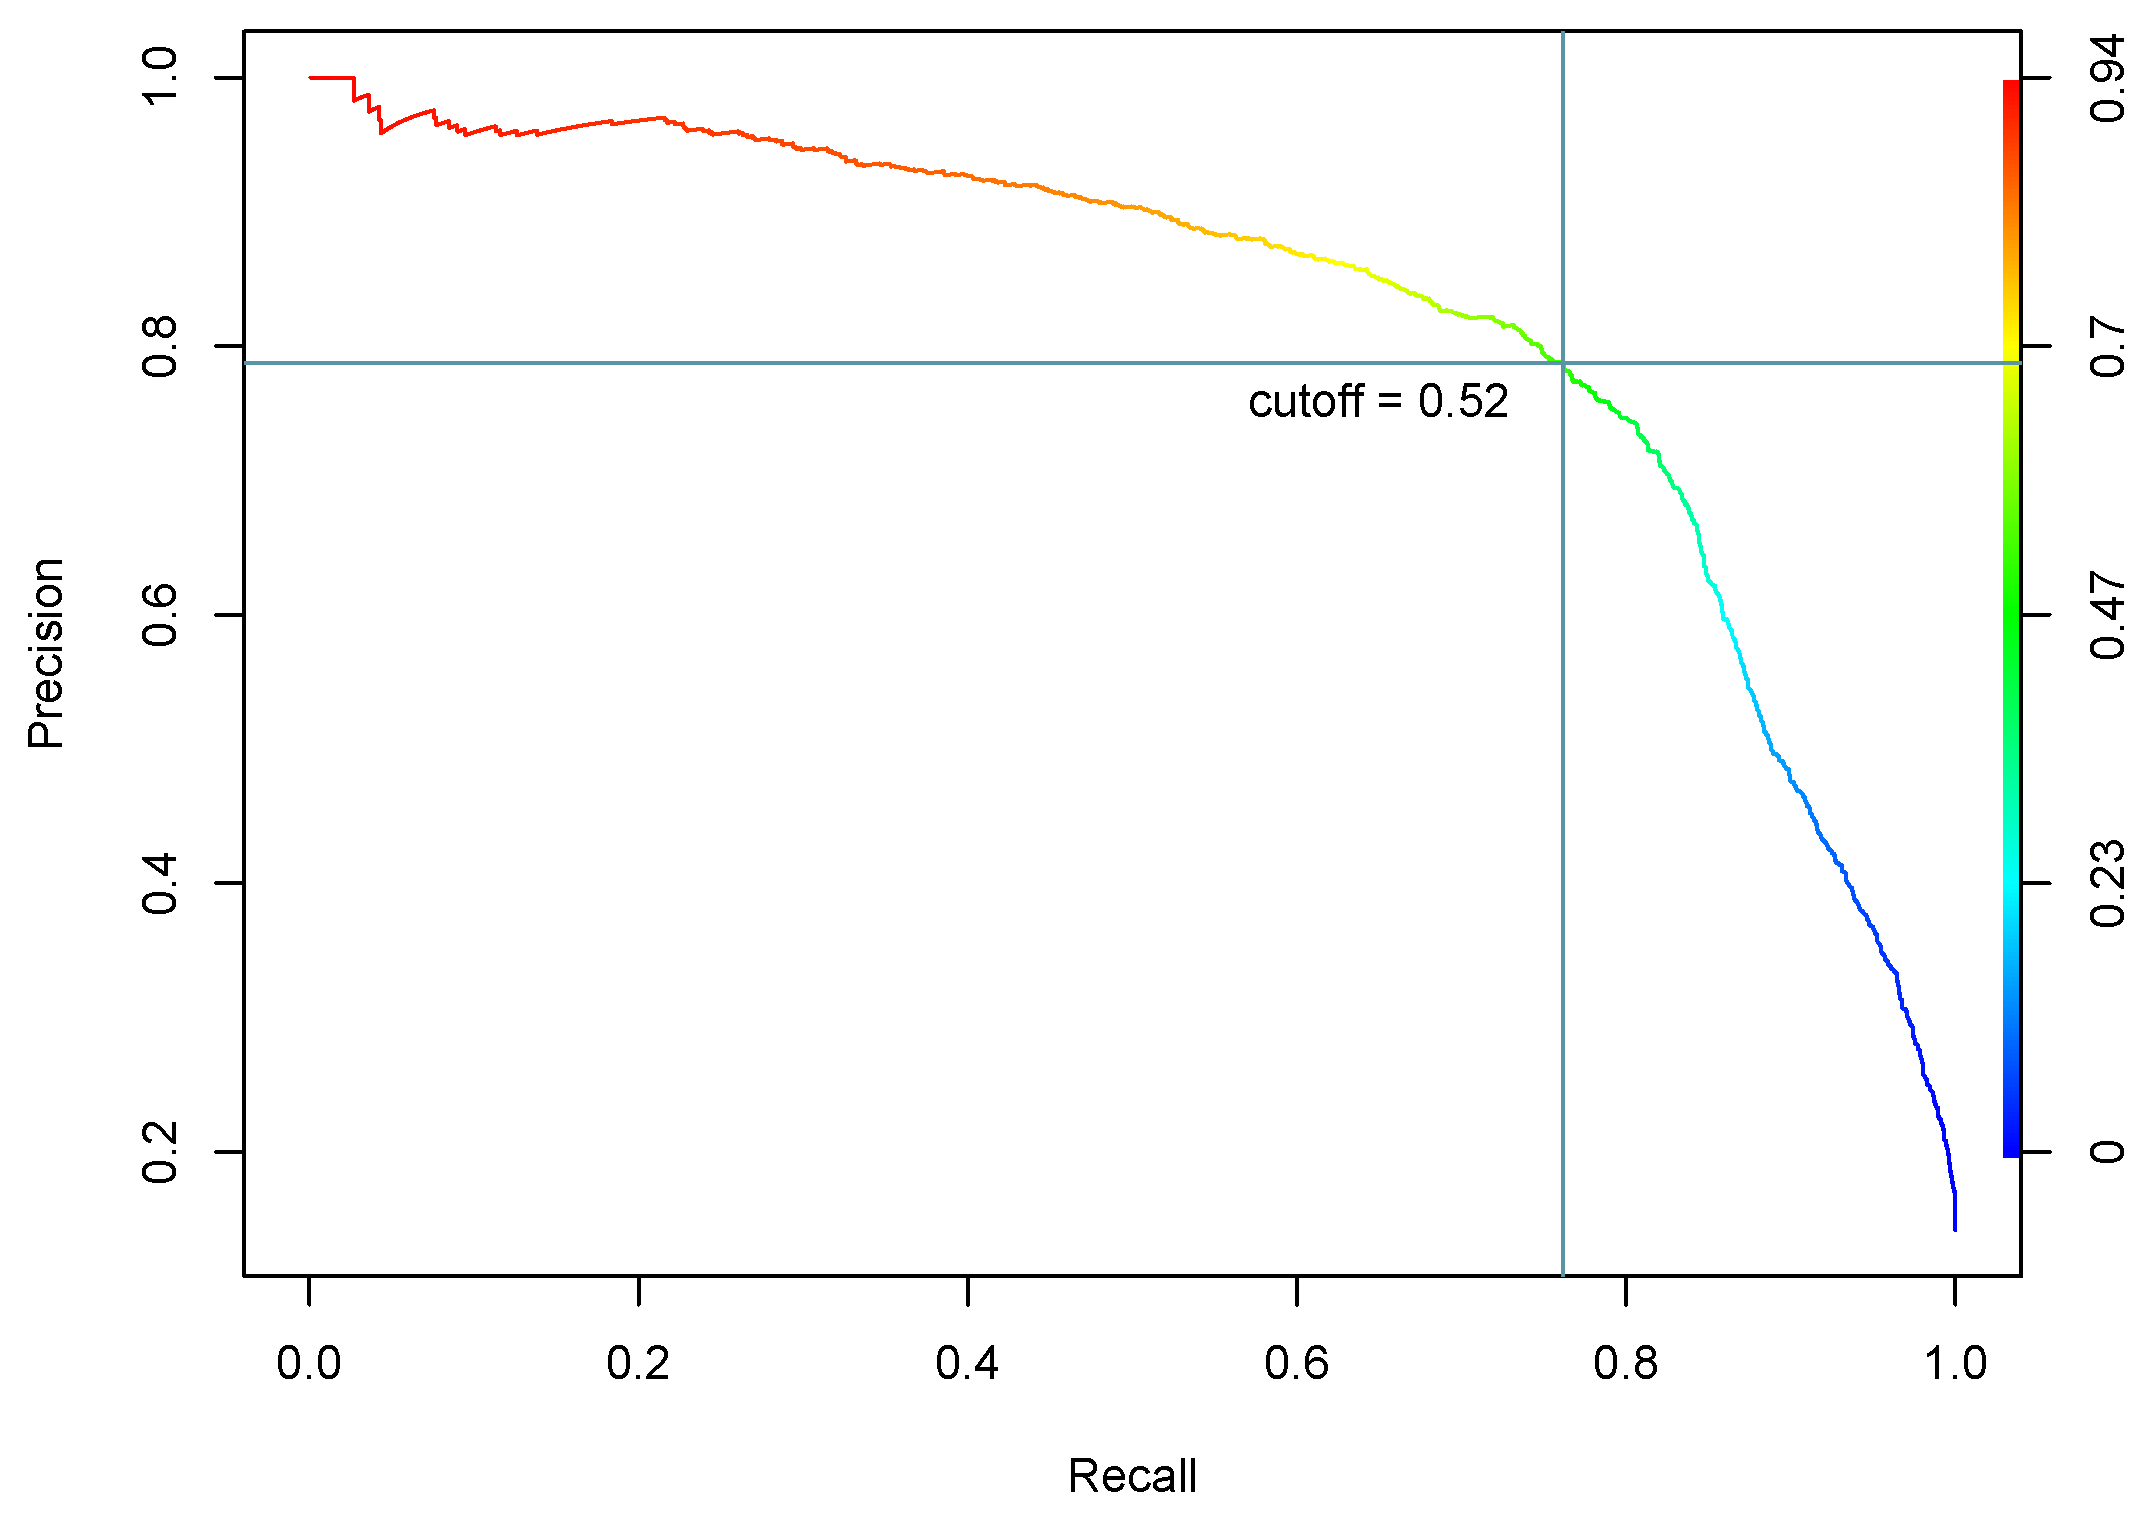
The AUC for Dataset 2 is 0.951, and the ROC curve is shown in Figure 12 with the best cutoff being 0.23, having a false positive rate of 0.100 and true positive rate of 0.864. The model without covariate effects has an AUC of 0.954. In this case, adding covariates decreases AUC, suggesting a worse fit. Figure 13 shows the respective precision and recalls at different cutoffs. The best cutoff for precision–recall is 0.520 with a precision of 0.787 and recall of 0.761. Compared to the high precision and recall values achieved in Dataset 1, the model for Dataset 2 does not have the same level of discriminative ability, indicating a weaker separation between true ties and non-ties.
Figure 12.
The ROC curve of the two covariate model for Dataset 2.
Figure 13.
The precision–recall curve of the two covariate model for Dataset 2.
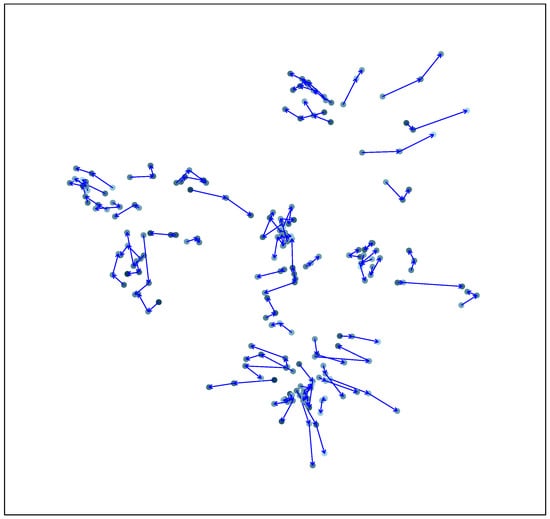
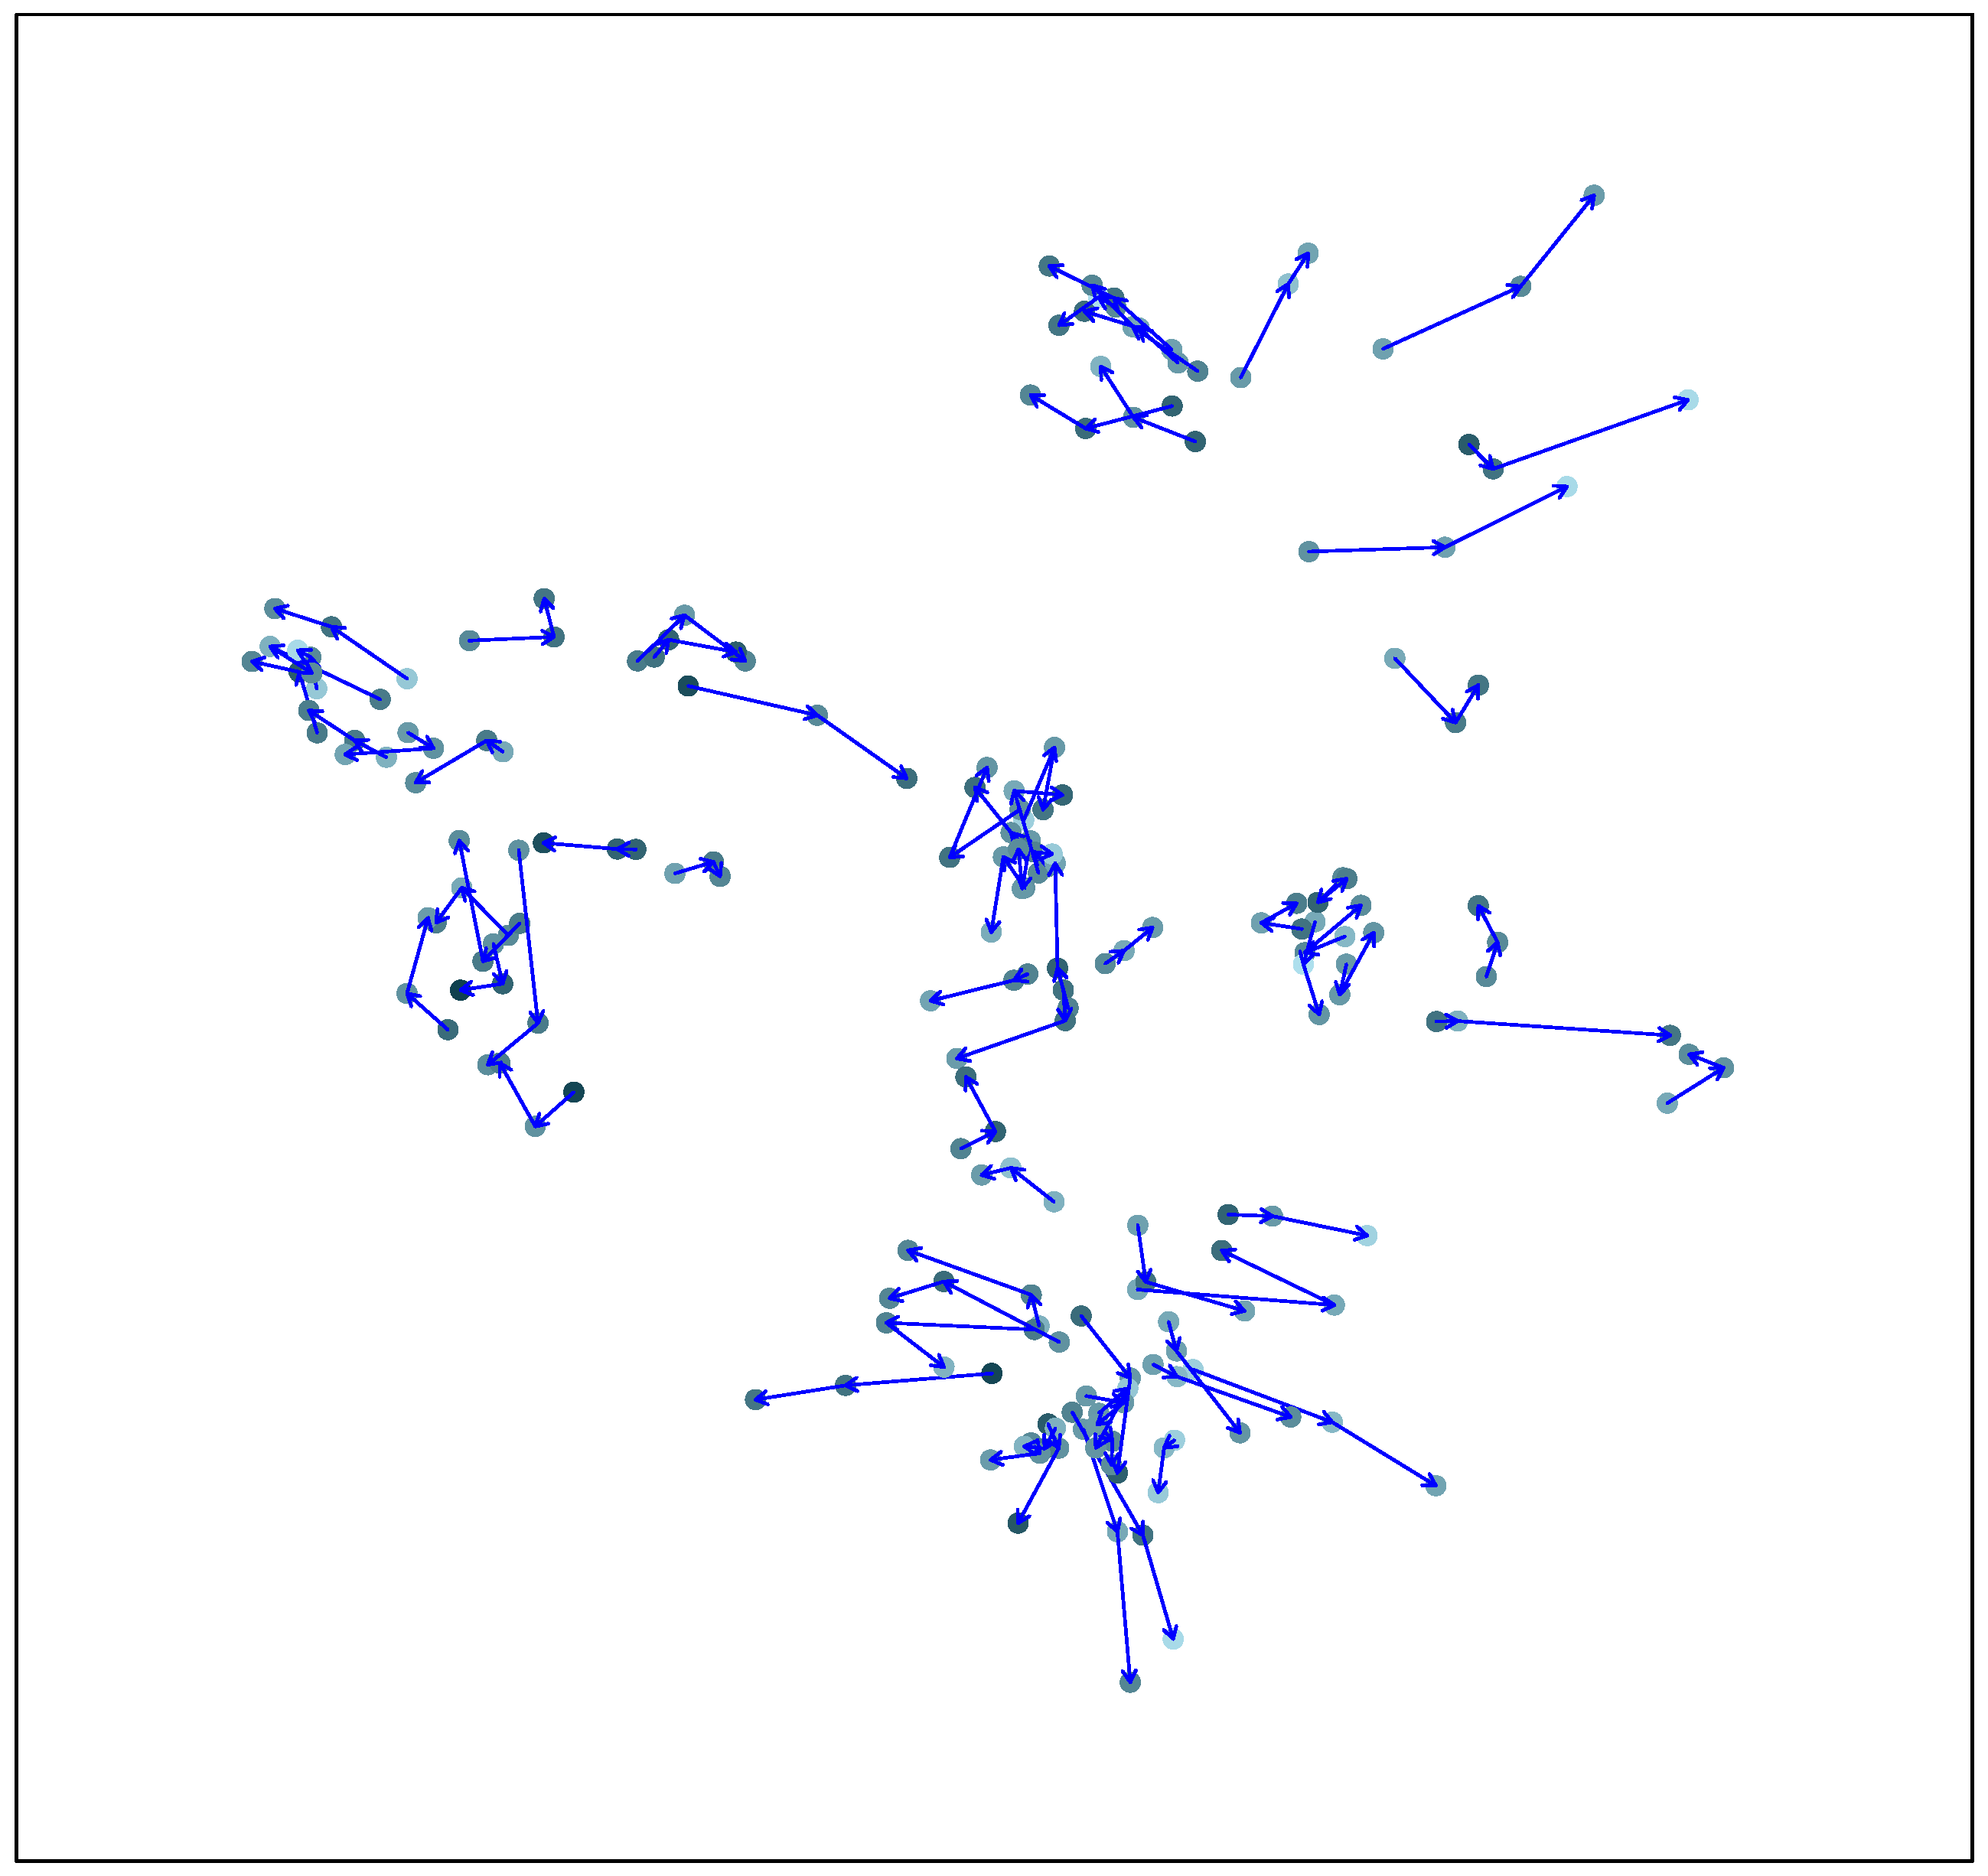
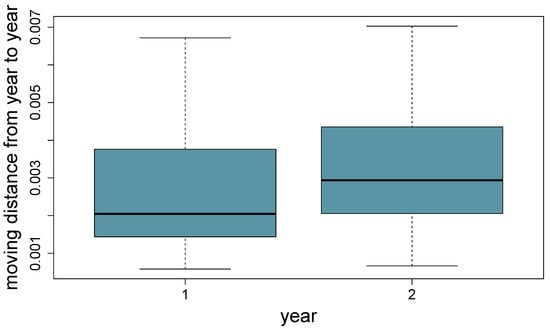
The movements of latent positions from year to year estimated by posterior means are shown in Figure 14. Movement distances for individuals vary quite a bit alongside with change in the covariate value of loneliness, as shown by the color of the latent positions. Despite individualized latent position movement trajectories, the latent positions tend to remain in the same area of the latent space across three years. Patterns of loneliness change tend to be varied by individuals as well, but in some clusters of latent positions that remained close, loneliness levels are also fairly close, showing a homophily effect. On the other hand, the average individual latent position movement for each time points (Figure 15) indicates a slightly larger average moving distance from year 2 to year 3 compared to that from year 1 to year 2.
Figure 14.
Latent positions of students with darker color dots indicating a larger value of the covariate of loneliness.
Figure 15.
Each individual’s moving distance in latent positions from year to year based on the actor-based evolution model.
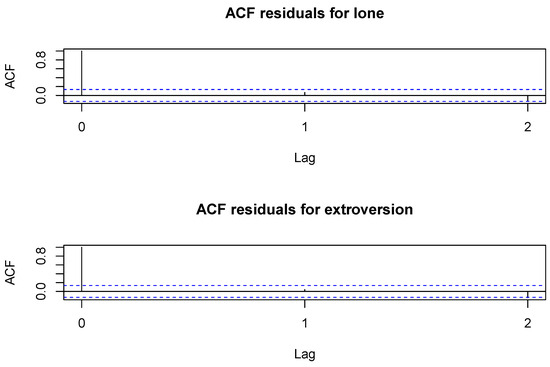
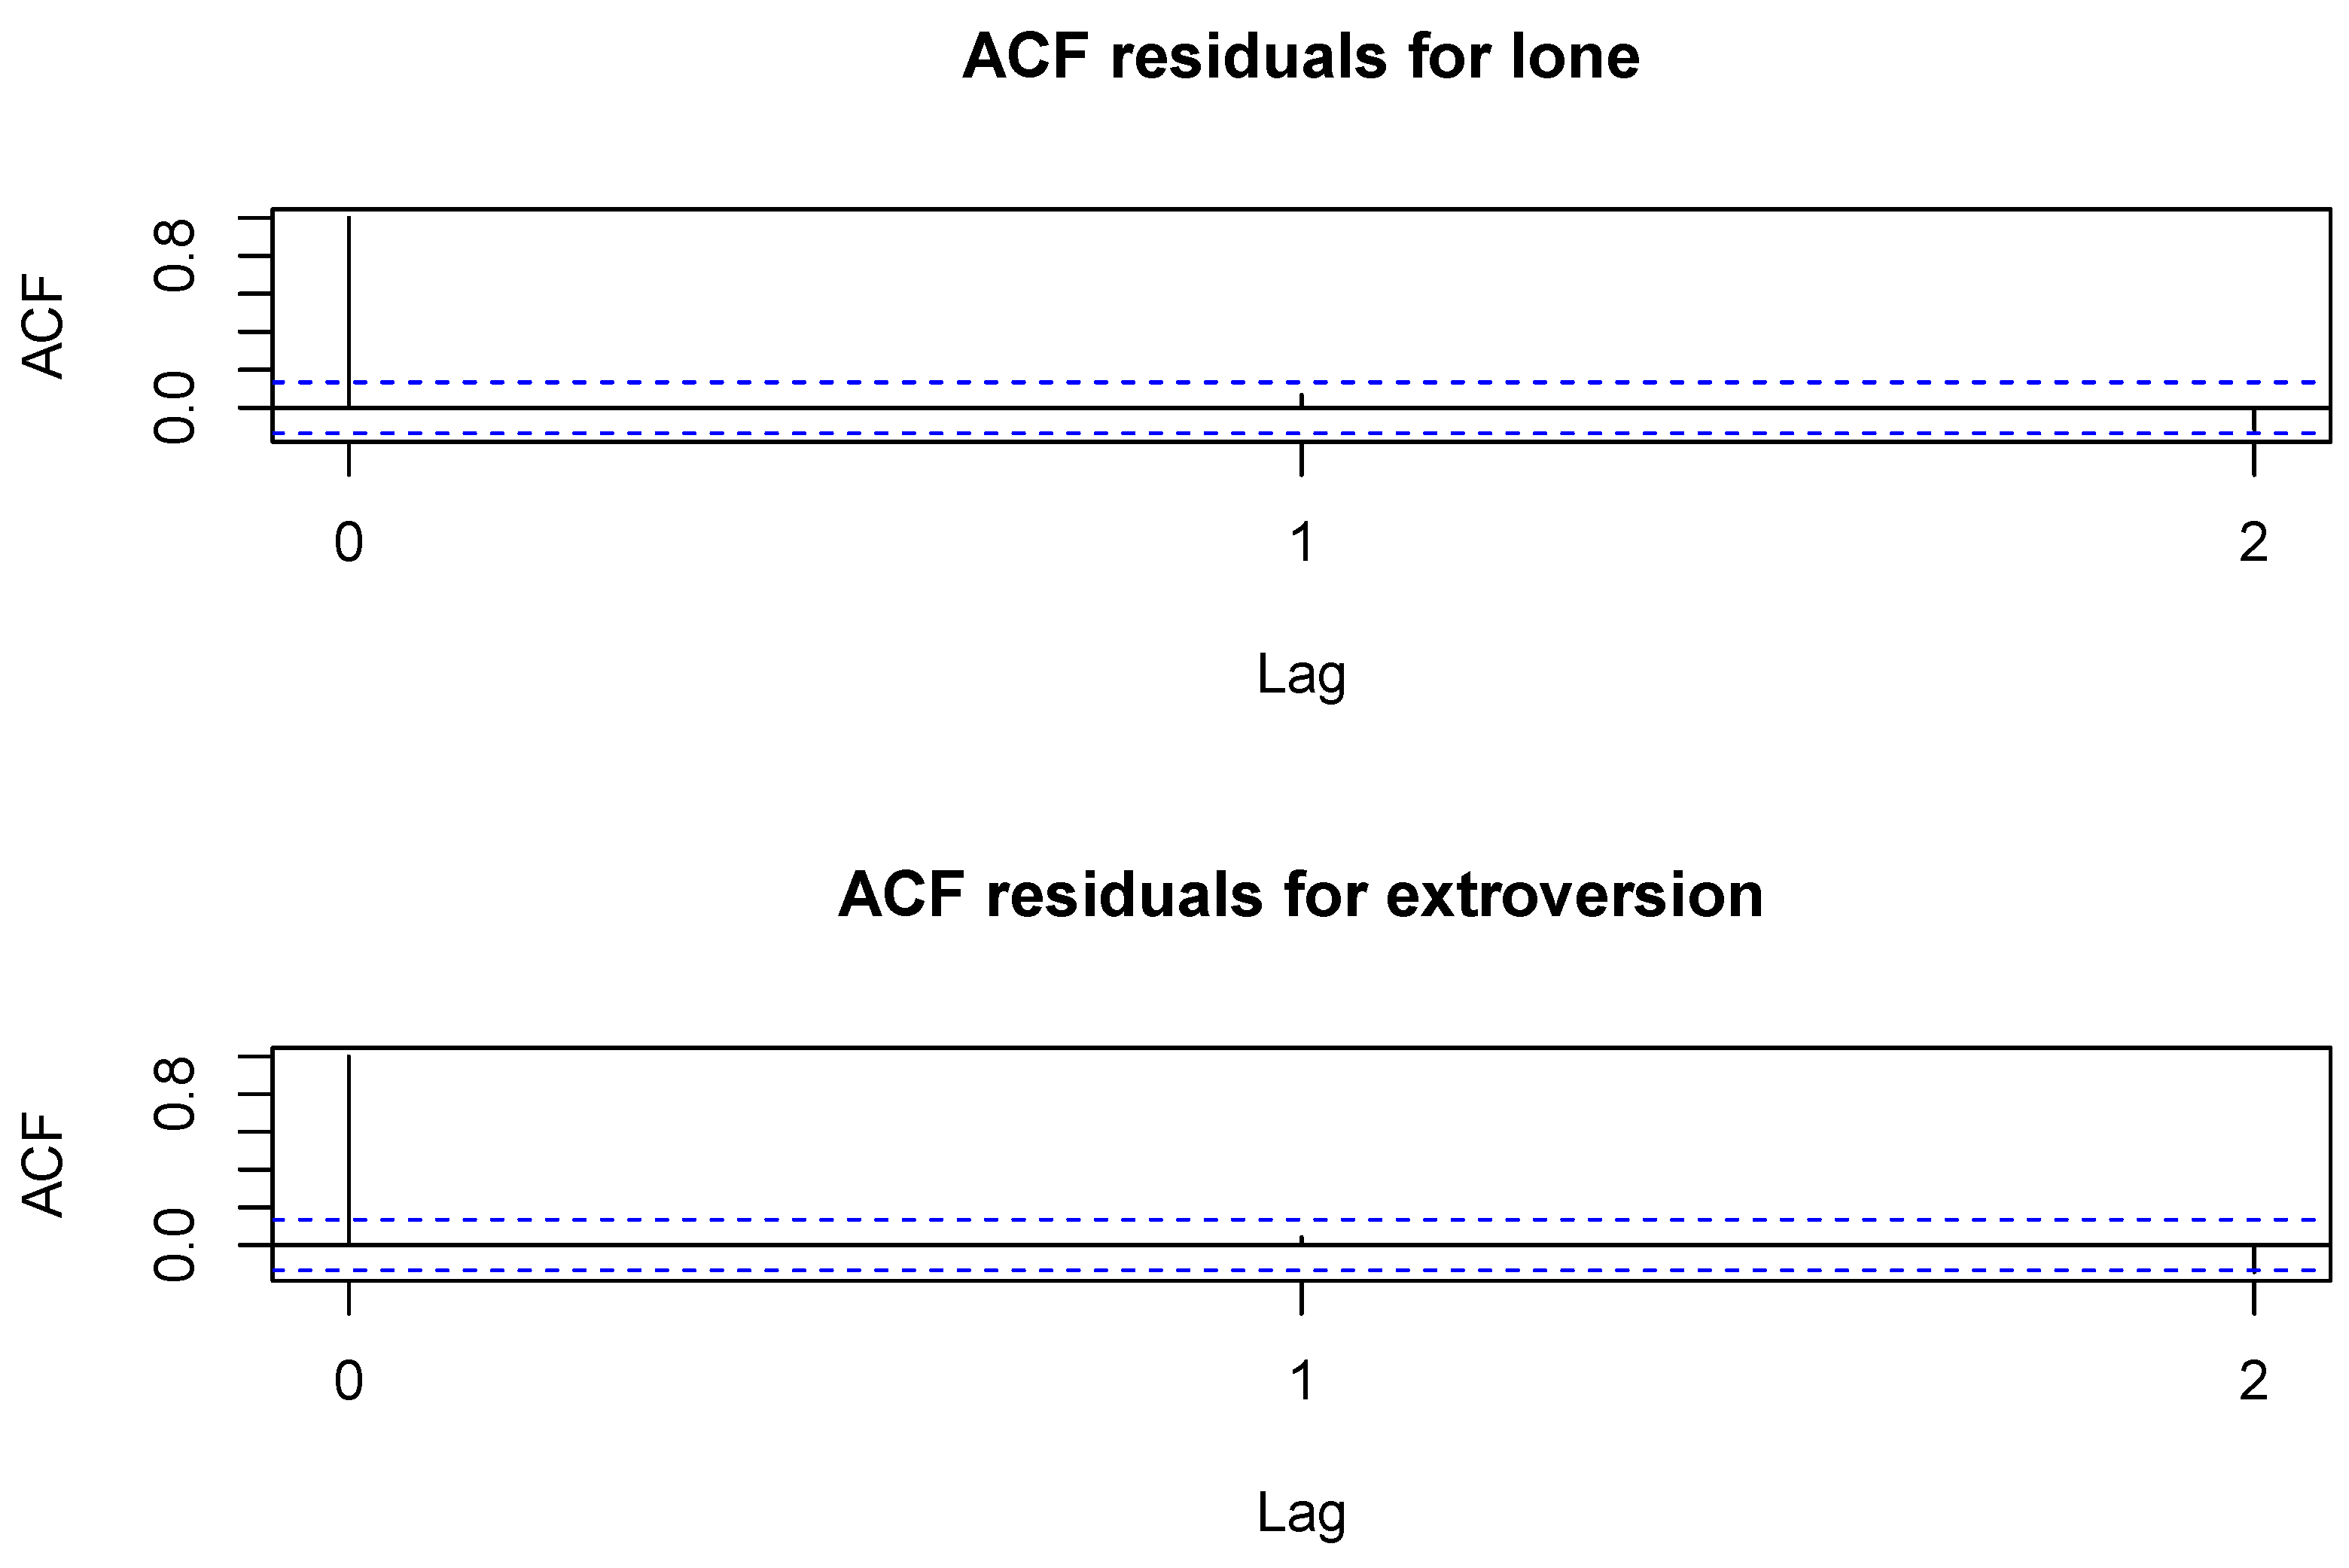
To assess whether the AR(1) process is appropriate for covariates in Dataset 2, autocorrelations of covariate residuals pooled across individuals after removing the AR(1) trends were plotted, as shown in Figure 16. Autocorrelations were all small, indicating that AR(1) is appropriate.
Figure 16.
Residual autocorrelation plots for covariates in Dataset 2. The blue horizontal lines indicate the 95% confidence limits under the null hypothesis of no autocorrelation.
4. Discussion
The current study proposes an extension of the DLSM that enhances the understanding of how relationships form and dissipate dynamically by considering time-varying covariates. The proposed model assumes that the observed network at each time point is a function of both latent positions and covariates. The latent positions and covariates themselves are also dynamic and evolve from time point to time point. Prior implementations of DLSM with dynamic covariates by Adhikari et al. [27] and Loyal [28] focused on the dynamic influence of covariates. The current paper is different because the evolution of the covariates themselves are investigated. Fitting this model to two friendship network datasets with a different number of time points and covariates, it is found that the latent positions and covariates contribute differently to friendship formation. In Dataset 1, friendship tends to form in the case when receivers have higher social event attendance, lower happiness, and higher pressure than the sender; in Dataset 2, friendship tends to form between receivers and senders when receivers have lower extroversion and higher loneliness. Overall, the covariate effect trend can be explained by senders being drawn to more visible and relatable receivers. In both datasets, latent position movements from time point to time point tend to be small, and the sender effect tends to dominate the observed network formation over receiver effects.
The proposed model can be expanded in several ways. First, in the current model, it is assumed that the covariates are continuous variables. However, in practical data analysis, other types of variables such as binary variables, ordinal variables, and categorical variables may exist. To incorporate such types of covariates, one can change the corresponding time series process to match the distributions underlying different data types. For example, binary data could have an AR process on the Bernoulli probability, which can then be used as a predictor to edges being present in social networks.
Second, network ties are dichotomized in the current paper. This choice reflects the research focus on the presence versus absence of ties rather than their intensity. While dichotomization simplifies interpretation and modeling, it does entail some loss of information compared to weighted networks. The framework can indeed be extended to networks with weighted edges, as Sewell and Chen [39] explored. In such a situation, the probability of edge formation can be modeled using an exponential link, if the edge is assumed to be continuous, or extending the logic link for ordinal edge values.
Third, when analyzing Dataset 2, composite scores for the loneliness scale and the extroversion scale are used. However, latent data analysis can be applied here, too. For example, multiple survey items might be used to measure the same unobserved construct (e.g., personality is often measured using a series of questions). In this case, a latent variable or a latent space for covariates would be more appropriate, as shown in the paper [40]. Ref. [40] describes a method that models covariates in static social networks via an attribute latent space model, which can possibly be extended to dynamic social networks.
Fourth, in the setup of the current model, correlations among covariates are not considered for simplicity, but such correlations can indeed be present in empirical data. It is possible to modify the independent autoregressive processes for each covariate to be a vector autoregressive process for all covariates together. Inspired by this possibility, one can also investigate different covariate evolution processes as well as latent position evolution processes.
Fifth, although the necessity of higher-order AR models is assessed using residual autocorrelation diagnostics, a systematic comparison with alternative time-series specifications is not conducted. In particular, whether other plausible evolution models such as random walk or more flexible state-space models might provide a better characterization of covariate dynamics is not evaluated. Future work could compare alternative temporal structures to assess their relative adequacy.
Sixth, the current analysis did not involve missing data. In the presence of missing values, imputation methods [41] or approaches that explicitly model the missingness mechanism [42] could be employed. Although the proposed model is built upon LSM, it can be extended to incorporate model-based eigenvalue decomposition methods [43].
Seventh, the predictive performances of the DLSM with and without covariates were compared in this paper, which sheds light on the potential drawbacks of having covariates. In Dataset 1, including covariates slightly improved AUC, suggesting that observed covariates capture some aspects of tie formation. In contrast, in Dataset 2, adding covariates slightly decreased AUC, indicating that the latent-space component may already account for most of the structure and including covariates can introduce noise or overfitting.
Eighth, the current paper is based on latent space model, which emphasizes the explanation of tie formation in temporal networks; in contrast, more general dynamic-graph sequence modeling approaches such as DyG-Mamba adopt a state-space paradigm that prioritizes predictive performance [44]. This reveals fundamental differences in modeling goals. While the DLSM aims to decompose observed network evolution into interpretable components, DyG-Mamba and similar state-space models aim to capture highly complex, nonlinear dynamics in a largely data-driven way. Thus, the DLSM is suitable for understanding roles of different components such as covariates and latent positions in network evolution, whereas state-space models are more suited for prediction. For future works, it could be valuable to investigate the role of covariates in state-space models as well.
Ninth, the empirical datasets used in this current study are not standard benchmark datasets, which raises issues of reproducibility and validity of the proposed models. Both datasets are friendship datasets collected via surveys in university settings and are specific to particular social contexts and populations. As a result, the findings of the current study may not be generalized to other types of networks in other environments. Gathering datasets for reproduction may also be difficult given the nature of friendship data and the longitudinal aspects of the datasets, further posing validation constraints.
Finally, the current sampling procedure is implemented in R. The computational time is not ignorable. While in Dataset 2, the chain of 1,000,000 iterations is finished in around 3 h on a Macbook Pro laptop with M1 chip, the chain of 700,000 iterations on Dataset 1 took around 7 h due to the much larger number of time points even with a relatively small sample size of . For larger sample sizes such as , the computational time with the same number of iterations and time points will be approximately seven-fold. The larger time points and iterations also pose a problem to memory usage because the MCMC chain saved could be so large as the iteration number increases that it could deplete the available memory on a machine. For example, the chain for Dataset 1, if saving every iteration, would take around 10 GBs of memory. The computing cost has prevented us from conducting any simulation studies. In the future, methods of speeding up the algorithm can be explored.
5. Conclusions
In this paper, an extension of the DLSM that incorporates the effects of time-varying covariates into the network evolution process is presented. Applying the model to two empirical datasets, our results show that whether covariates can explain information in the network beyond what the latent positions entail depends on the dataset. In Dataset 1, adding covariate evolution results in slightly higher AUC, whereas in Dataset 2, adding covariates decreases AUC. Future research could extend this work by modeling valued ties, considering covariates with different data types, applying the framework to larger networks, and comparing it to alternative dynamic graph sequence approaches such as DyG-Mamba. Such extensions would enhance both the predictive power and interpretability of dynamic network models in applied contexts. It should also be noted that the current work can be further validated by applying DLSM with covariates to standard benchmark datasets.
Author Contributions
Conceptualization, Z.X. and Z.Z.; methodology, Z.X.; software, Z.X.; validation, Z.Z.; formal analysis, Z.X.; investigation, Z.X. and Z.Z.; resources, Z.Z.; data curation, Z.Z.; writing—original draft preparation, Z.X.; writing—review and editing, Z.Z.; visualization, Z.X.; supervision, Z.Z.; project administration, Z.Z.; funding acquisition, Z.Z. All authors have read and agreed to the published version of the manuscript.
Funding
This work was supported by a grant from the Department of Education (R305D210023). However, the contents do not necessarily represent the policy of the Department of Education, and you should not assume endorsement by the Federal Government.
Institutional Review Board Statement
The data collection in this study was approved under IRB protocol 20-08-6186.
Informed Consent Statement
Informed consent was obtained from all subjects involved in the study.
Data Availability Statement
The raw data supporting the conclusions of this article will be made available by the authors on request.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Tang, K.Y.; Chang, C.Y.; Hwang, G.J. Trends in artificial intelligence-supported e-learning: A systematic review and co-citation network analysis (1998–2019). Interact. Learn. Environ. 2023, 31, 2134–2152. [Google Scholar] [CrossRef] [Scilit]
- Urlings, M.J.; Duyx, B.; Swaen, G.M.; Bouter, L.M.; Zeegers, M.P. Citation bias and other determinants of citation in biomedical research: Findings from six citation networks. J. Clin. Epidemiol. 2021, 132, 71–78. [Google Scholar] [CrossRef] [Scilit]
- Van der Horst, M.; Coffé, H. How friendship network characteristics influence subjective well-being. Soc. Indic. Res. 2012, 107, 509–529. [Google Scholar] [CrossRef] [Scilit]
- Eagle, N.; Pentland, A.; Lazer, D. Inferring friendship network structure by using mobile phone data. Proc. Natl. Acad. Sci. USA 2009, 106, 15274–15278. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Liu, H.; Jin, I.H.; Zhang, Z. Structural Equation Modeling of Social Networks: Specification, Estimation, and Application. Multivar. Behav. Res. 2018, 53, 714–730. [Google Scholar] [CrossRef] [Scilit]
- Liu, H.; Zhang, Z. Birds of a Feather Flock Together and Opposites Attract: The Nonlinear Relationship Between Personality and Friendship. J. Behav. Data Sci. 2021, 1, 34–52. [Google Scholar] [CrossRef] [Scilit]
- Xu, Z.; Zhang, Z. Structural Equation Models with Social Networks. Struct. Equ. Model. Multidiscip. J. 2025, 33, 124–133. [Google Scholar] [CrossRef] [Scilit]
- El-Sayed, A.M.; Scarborough, P.; Seemann, L.; Galea, S. Social network analysis and agent-based modeling in social epidemiology. Epidemiol. Perspect. Innov. 2012, 9, 1–9. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Vasylyeva, T.I.; Friedman, S.R.; Paraskevis, D.; Magiorkinis, G. Integrating molecular epidemiology and social network analysis to study infectious diseases: Towards a socio-molecular era for public health. Infect. Genet. Evol. 2016, 46, 248–255. [Google Scholar] [CrossRef] [Scilit]
- Ravazzi, C.; Dabbene, F.; Lagoa, C.; Proskurnikov, A.V. Learning hidden influences in large-scale dynamical social networks: A data-driven sparsity-based approach, in memory of roberto tempo. IEEE Control Syst. Mag. 2021, 41, 61–103. [Google Scholar] [CrossRef] [Scilit]
- Veenstra, R.; Bertogna, T.; Laninga-Wijnen, L. The growth of longitudinal social network analysis: A review of the key data sets and topics in research on child and adolescent development. Teen Friendsh. Netw. Dev. Risky Behav. 2023, 326–352. [Google Scholar]
- Hoff, P.D.; Raftery, A.E.; Handcock, M.S. Latent space approaches to social network analysis. J. Am. Stat. Assoc. 2002, 97, 1090–1098. [Google Scholar] [CrossRef] [Scilit]
- Sewell, D.K.; Chen, Y. Latent space models for dynamic networks. J. Am. Stat. Assoc. 2015, 110, 1646–1657. [Google Scholar] [CrossRef] [Scilit]
- Leifeld, P.; Cranmer, S.J.; Desmarais, B.A. Temporal exponential random graph models with btergm: Estimation and bootstrap confidence intervals. J. Stat. Softw. 2018, 83, 1–36. [Google Scholar] [CrossRef] [Scilit]
- Snijders, T.A. Stochastic actor-oriented models for network dynamics. Annu. Rev. Stat. Its Appl. 2017, 4, 343–363. [Google Scholar] [CrossRef] [Scilit]
- Leifeld, P.; Cranmer, S.J. A theoretical and empirical comparison of the temporal exponential random graph model and the stochastic actor-oriented model. Netw. Sci. 2019, 7, 20–51. [Google Scholar] [CrossRef] [Scilit]
- Matias, C.; Miele, V. Statistical clustering of temporal networks through a dynamic stochastic block model. J. R. Stat. Soc. Ser. Stat. Methodol. 2017, 79, 1119–1141. [Google Scholar] [CrossRef] [Scilit]
- Cranmer, S.J.; Leifeld, P.; McClurg, S.D.; Rolfe, M. Navigating the range of statistical tools for inferential network analysis. Am. J. Political Sci. 2017, 61, 237–251. [Google Scholar] [CrossRef] [Scilit]
- An, W. Friendship network formation in Chinese middle schools: Patterns of inequality and homophily. Soc. Netw. 2022, 68, 218–228. [Google Scholar] [CrossRef] [Scilit]
- McMillan, C. Strong and weak tie homophily in adolescent friendship networks: An analysis of same-race and same-gender ties. Netw. Sci. 2022, 10, 283–300. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Cao, Q.K.; Dabelko-Schoeny, H.; Warren, K.; Lee, M.Y. Does network homophily persist in multicultural volunteering programs? Results from an Exponential Random Graph Model. J. Migr. Health 2024, 10, 100256. [Google Scholar] [CrossRef] [Scilit]
- Wang, X.Y.; Chen, B.; Hou, N.; Chi, Z.P. Evolution of structural properties of the global strategic emerging industries’ trade network and its determinants: An TERGM analysis. Ind. Mark. Manag. 2024, 118, 78–92. [Google Scholar] [CrossRef] [Scilit]
- Rogoza, R.; Danieluk, B.; Kowalski, C.M.; Kwiatkowska, K.; Kwiatkowska, M.M. Making and maintaining relationships through the prism of the dark triad traits: A longitudinal social network study. J. Personal. 2021, 89, 338–356. [Google Scholar] [CrossRef] [Scilit]
- Kalish, Y. Stochastic actor-oriented models for the co-evolution of networks and behavior: An introduction and tutorial. Organ. Res. Methods 2020, 23, 511–534. [Google Scholar] [CrossRef] [Scilit]
- Chu, A.M.; Chan, L.S.; So, M.K. Stochastic actor-oriented modelling of the impact of COVID-19 on financial network evolution. Stat 2021, 10, e408. [Google Scholar] [CrossRef] [Scilit]
- Olivella, S.; Pratt, T.; Imai, K. Dynamic stochastic blockmodel regression for network data: Application to international militarized conflicts. J. Am. Stat. Assoc. 2022, 117, 1068–1081. [Google Scholar] [CrossRef] [Scilit]
- Adhikari, S.; Sweet, T.; Junker, B. Analysis of longitudinal advice-seeking networks following implementation of high stakes testing. J. R. Stat. Soc. Ser. Stat. Soc. 2021, 184, 1475–1500. [Google Scholar] [CrossRef] [Scilit]
- Loyal, J.D. Fast variational inference of latent space models for dynamic networks using Bayesian P-splines. arXiv 2024, arXiv:2401.09715. [Google Scholar] [CrossRef] [Scilit]
- Zhao, S.; Zhang, Z.; Zhang, H. Bayesian Inference of Dynamic Mediation Models for Longitudinal Data. Struct. Equ. Model. Multidiscip. J. 2024, 31, 14–26. [Google Scholar] [CrossRef] [Scilit]
- Liu, H.; Jin, I.H.; Zhang, Z.; Yuan, Y. Social Network Mediation Analysis: A Latent Space Approach. Psychometrika 2021, 86, 272–298. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Sarkar, P.; Moore, A.W. Dynamic social network analysis using latent space models. ACM SIGKDD Explor. Newsl. 2005, 7, 31–40. [Google Scholar] [CrossRef] [Scilit]
- R Core Team. R: A Language and Environment for Statistical Computing; R Foundation for Statistical Computing: Vienna, Austria, 2021. [Google Scholar]
- Eddelbuettel, D.; Balamuta, J.J. Extending R with C++: A brief introduction to Rcpp. Am. Stat. 2018, 72, 28–36. [Google Scholar] [CrossRef] [Scilit]
- Eddelbuettel, D.; Sanderson, C. RcppArmadillo: Accelerating R with high-performance C++ linear algebra. Comput. Stat. Data Anal. 2014, 71, 1054–1063. [Google Scholar] [CrossRef] [Scilit]
- Russell, D.W. UCLA Loneliness Scale (Version 3): Reliability, validity, and factor structure. J. Personal. Assess. 1996, 66, 20–40. [Google Scholar] [CrossRef] [Scilit]
- Donnellan, M.B.; Oswald, F.L.; Baird, B.M.; Lucas, R.E. The mini-IPIP scales: Tiny-yet-effective measures of the Big Five factors of personality. Psychol. Assess. 2006, 18, 192. [Google Scholar] [CrossRef] [Scilit]
- Geweke, J. Evaluating the Accuracy of Sampling-Based Approaches to the Calculation of Posterior Moments; Technical report; Federal Reserve Bank of Minneapolis: Minneapolis, MN, USA, 1991. [Google Scholar]
- Du, H.; Ke, Z.; Jiang, G.; Huang, S. The Performances of Gelman-Rubin and Geweke’s Convergence Diagnostics of Monte Carlo Markov Chains in Bayesian Analysis. J. Behav. Data Sci. 2022, 2, 47–72. [Google Scholar] [CrossRef] [Scilit]
- Sewell, D.K.; Chen, Y. Latent space models for dynamic networks with weighted edges. Soc. Netw. 2016, 44, 105–116. [Google Scholar] [CrossRef] [Scilit]
- Wang, S.; Paul, S.; De Boeck, P. Joint Latent Space Model for Social Networks with Multivariate Attributes. Psychometrika 2023, 88, 1197–1227. [Google Scholar] [CrossRef] [Scilit]
- Xu, Z.; Hai, J.; Yang, Y.; Zhang, Z. Comparison of Methods for Imputing Social Network Data. J. Data Sci. 2022, 21, 599–618. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Z.; Wang, L. A note on the robustness of a full Bayesian method for nonignorable missing data analysis. Braz. J. Probab. Stat. 2012, 26, 244–264. [Google Scholar] [CrossRef] [Scilit]
- Che, C.; Jin, I.H.; Zhang, Z. Network Mediation Analysis Using Model-Based Eigenvalue Decomposition. Struct. Equ. Model. Multidiscip. J. 2020, 28, 148–161. [Google Scholar] [CrossRef] [Scilit]
- Li, D.; Tan, S.; Zhang, Y.; Jin, M.; Pan, S.; Okumura, M.; Jiang, R. Dyg-mamba: Continuous state space modeling on dynamic graphs. arXiv 2024, arXiv:2408.06966. [Google Scholar]
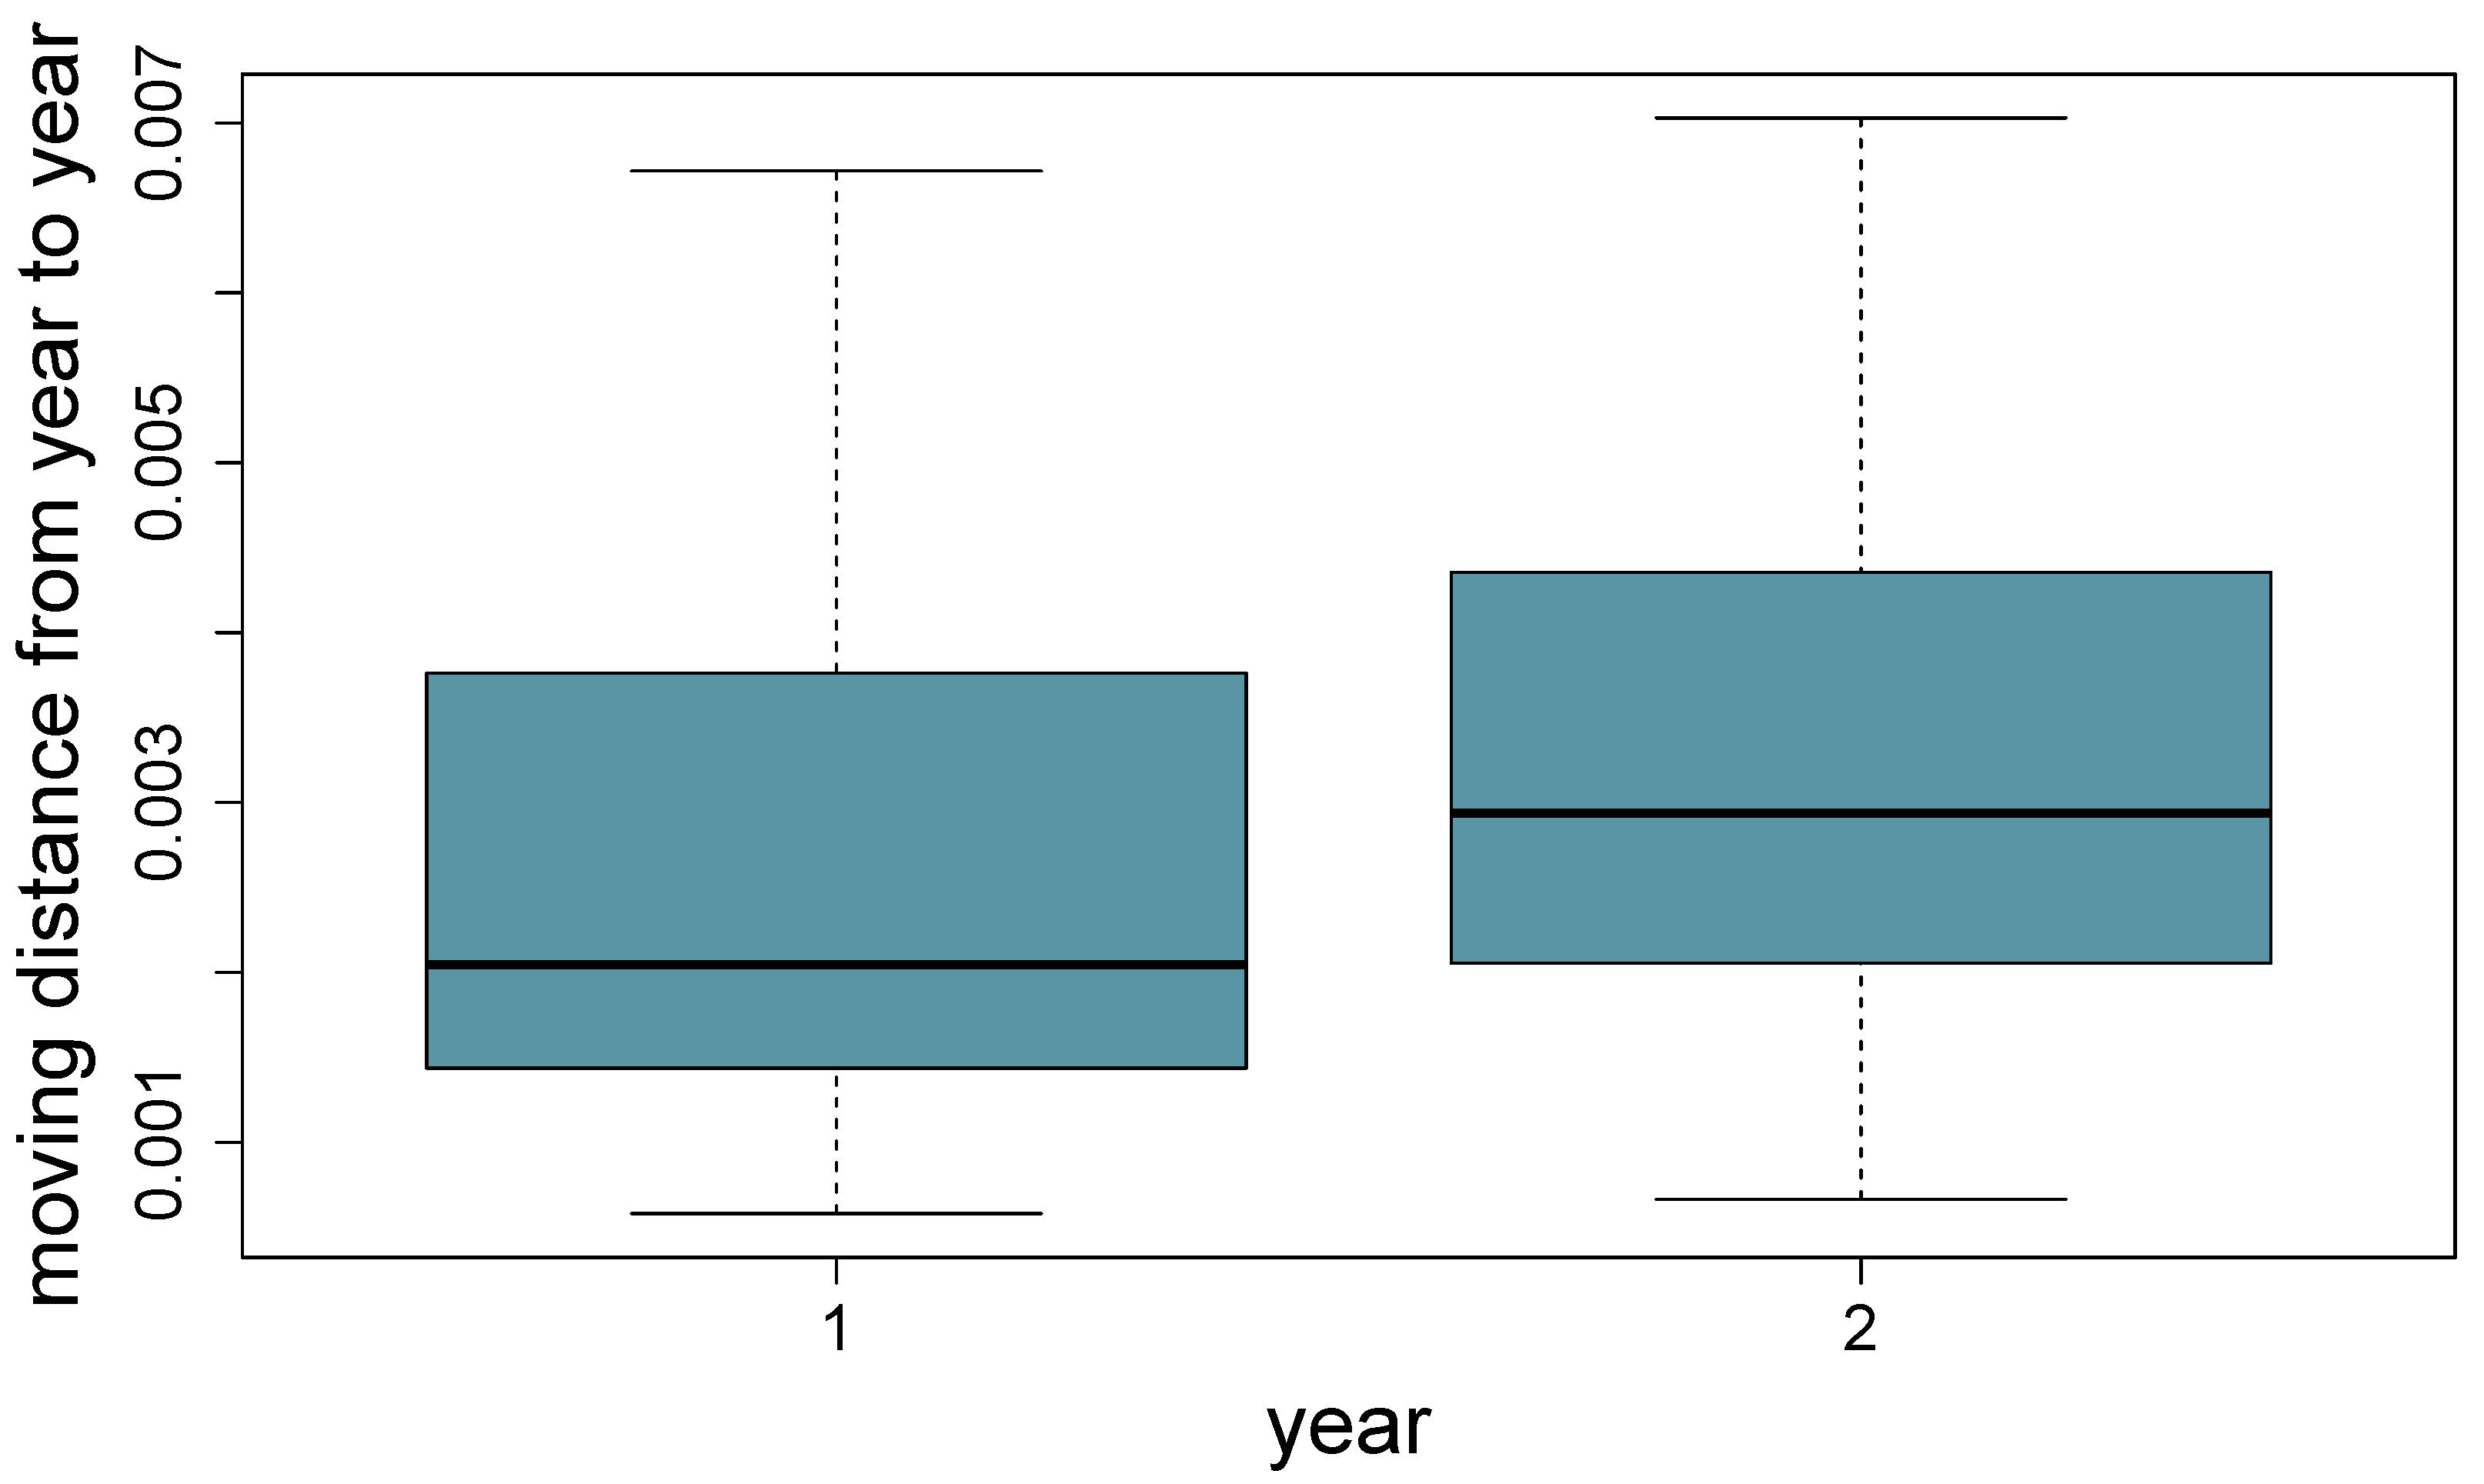

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.