


Abstract
The objective of the next POI recommendation is using the historical check-in sequences of users to learn the preferences and habits of users, providing a list of POIs that users will be inclined to visit next. Then, there are some limitations in existing POI recommendation algorithms. On the one hand, after obtaining the user’s preferences for the current period, if we consider the entire historical check-in sequence, including future check-in information, it is susceptible to the influence of noisy data, thereby reducing the accuracy of recommendations. On the other hand, the current methods generally rely on modeling long- and short-term preferences within a fixed time window, which possibly leads to an inability to capture users’ behavior characteristics at different time scales. As a result, we proposed a Multimodal Temporal Fusion for Next POI Recommendation(MTFNR). Firstly, to understand users’ preferences and habits at different periods, multiple hypergraph neural networks are constructed to analyze user behavior patterns at different stages, and in order to avoid introducing interference factors, only the check-in sequences visited in the current period are considered to reduce the impact of noise on the model’s recommendation performance. Secondly, modeling the next POI recommendation task through the fusion of time information and long- and short-term preferences in order to gain a more comprehensive understanding of users’ preferences and habits, enhance the timeliness of recommendations, and improve the accuracy of recommendations. Lastly, introducing spatio-temporal interval information into the GRU model, capturing dependencies in sequences to improve the overall performance of the model. Extensive experiments on the real LBSN datasets demonstrated the superior performance of the MTFNR model. The experimental results indicate that Top-10 recall improved 2.81% to 15.97% compared to current methods.
1. Introduction
With the rapid development of mobile Internet and big data technology, location-based services has already undergone changes in various aspects of people’s lives. Interest points are the core component of LBS, they refer to places that users are interested in or have some special meaning to them, such as restaurants, parks, shopping malls, and so on. The next POI location recommendation technology [1,2] is based on users’ interests, historical behavior, and contextual information to recommend locations that may be of interest to users in order to meet their personalized needs. The research and application of the next POI location recommendation are constantly developing; with the advancement of POI location recommendation technology and the adaptation to different user needs, its potential value and application scenarios [3] are constantly expanding.
In prior research, traditional point-of-interest recommendation algorithms, much like other conventional recommendation systems, primarily relied on Matrix Factorization (MF) [4,5,6] or Markov Chain (MC) [7,8,9]. With the subsequent advancement of deep learning technologies, Recurrent Neural Networks (RNNs) and their variants [10,11], along with the Self-Attention Mechanism [12,13,14], demonstrated superior performance in processing sequential data. As a result, these methods gradually superseded traditional recommendation algorithms and were widely adopted as foundational frameworks in next-generation point-of-interest recommendation systems, becoming core components of the next-generation POI recommendation architecture. Following the evolution of neural network models, modern Graph Neural Networks (GNNs) [15,16] were introduced and also exhibited exceptional performance in the field of location recommendation. By transforming the aforementioned collaborative signals into graph structures, the correlations between POIs can be effectively modeled using GNNs. Recent studies have indicated that modeling more complex and fine-grained user–POI relationships represents a significant direction for improving POI recommendation systems. Moreover, Hypergraph Neural Networks (HGNNs) have demonstrated superior performance over GNNs in alleviating the cold-start problem, leading to an increasing trend wherein HGNNs are being adopted in a growing number of POI recommendation systems, a development that is considered inevitable.
Although the above methods have achieved significant success, there is still room for improvement in recommendation performance. Current methods have three main limitations.
First, when obtaining a user’s current interest preferences, considering the entire historical check-in sequence is susceptible to noise, which may introduce information inconsistent with the user’s current state and reduce recommendation accuracy. Our proposed model only utilizes the check-in sequence prior to the target time to learn user preferences, avoiding interference from future information. For example, in Figure 1, the reason a user chooses to visit a bar at 20:00 is that they usually need to relax at entertainment venues after work, rather than because they want to go home first.
Figure 1.
A location-based example illustrates the impact of long- and short-term preferences and temporal information on the next POI recommendation. The figure shows the user’s spatial distribution at different times. Starting from home and moving to the workplace, the user ultimately chooses the gym in the evening, reflecting the influence of both preference dynamics and temporal context.
Second, existing methods generally rely on fixed time windows [17] to model long- and short-term preferences, which may fail to capture user behavior patterns at different temporal scales, as users have varying interests at different times. Our model adaptively captures multi-scale long- and short-term preferences, flexibly reflecting temporal changes in user interests. For instance, in Figure 1, a month ago the user frequently went to the gym, recently often worked overtime, but in recent days prefers to relax at bars with friends.
Third, comprehensively capturing users’ temporal preferences remains challenging. Generally, when choosing to visit a POI, users are influenced by both time information and long- and short-term preferences [18]. Our model integrates time information with long- and short-term preferences to more accurately predict the user’s current interests. For example, in Figure 1, the user tends to visit bars or gyms around 20:00 based on time information, and combining long- and short-term preferences further clarifies which type of venue they currently prefer.
Through these improvements, our model effectively leverages historical check-in data, flexibly captures multi-scale preferences, and incorporates temporal information to provide more accurate recommendations, thereby addressing the limitations of existing methods related to noise, fixed time windows, and insufficient modeling of temporal preferences.
In this work, we propose a Multimodal Temporal Fusion for Next POI Recommendation (MTFNR) to address the aforementioned challenges. For the first issue, we argue that leveraging only the check-in records prior to the target time allows for a more accurate inference of the user’s current periodic preferences and habits, thereby mitigating the influence of noise. For the second issue, we employ hypergraph neural networks [19,20], which are capable of capturing complex multivariate and higher-order correlations beyond the ability of conventional Graph Neural Networks (GNNs) [21,22]. Specifically, we construct multiple hypergraph networks with varying temporal spans to learn user interest preferences across different time scales. To address the third issue, we enhance temporal modeling by fusing time-aware signals with long- and short-term preferences. Specifically, the model first extracts time-aware signals from check-in timestamps to capture users’ behavioral patterns at different times; it then separately models long-term stable preferences and short-term transient interests to reflect both habitual and situational needs; finally, the two components are integrated through a weighted fusion mechanism to balance time-specific behaviors and long-term trends. This fusion mechanism allows MTFNR to more accurately predict users’ current preferences while taking into account both their general interests and the relevance of the current temporal context, thereby improving the timeliness and practicality of recommendations.
Furthermore, building upon the GRU architecture [23,24], MTIFN incorporates user-specific spatio-temporal interval information [25], effectively capturing dependencies within check-in sequences, enhancing the robustness of the recommendation system, and overall improving recommendation performance.
The main innovations in our work can be summarized as follows:
- We propose a Long- and Short-Term Hypergraph Network (LSTHN) to dynamically capture users’ preference patterns across different time periods. Unlike existing static hypergraph methods, LSTHN constructs multiple period-specific hypergraphs to decouple behavioral patterns from different time segments. This design critically addresses the issues of behavioral noise and preference drift in long-term historical data. By focusing on contextual information from the current period, it achieves more precise user representation learning.
- We propose a Temporal Information-Aware Hypergraph Network (TIHN) to achieve fine-grained modeling of users’ dynamic preferences. By constructing temporal hypergraphs, this method effectively captures the variation patterns of POI functional value over time and captures the periodic patterns of user behavior along the temporal dimension. Ultimately, TIHN ensures deep alignment between recommendation results and users’ current spatio-temporal context, fundamentally enhancing both service accuracy and user experience.
- We designed a novel Multimodal Temporal Fusion Network for Recommendation (MTFNR), which employs a gated fusion mechanism to collaboratively model long- and short-term preferences. The core of the model lies in a learnable adaptive gating unit that dynamically balances the relative importance of long-term stable preferences and short-term preferences for the next recommendation. This explicit fusion strategy overcomes the limitations of simple concatenation or static weighting methods, thereby significantly enhancing the timeliness and accuracy of recommendation results.
- We conducted extensive experiments on multiple real-world datasets, the results of which not only validate the overall superiority of the MTFNR model but also provide an in-depth analysis of its core components.
2. Related Work
2.1. Next POI Recommendation
POI recommendation aims to recommend future points of interest visits to users based on check-in sequences. Early research mainly used matrix factorization (MF) [5,6,26] and Markov chain (MC) [8,9] algorithms for recommendation. Koren et al. [4] designed a common method to solve recommendation problems, namely learning potential representations of users and POIs through MF. With the support of MC, it helps users meet their needs and hobbies in different situations. In addition, Markov chain (MC) models user behavior to form a transition matrix. Due to the large amount of data, a transition matrix cube was formed. To obtain an estimate of the user’s action or sequence preference, a personalized factor decomposition-based Monte Carlo (FPMC) model has been proposed by Rendle et al. [27], which is used for preference estimation of transition cubes, ultimately achieving a highly accurate position recommendation technique. Furthermore, traditional trip recommendation methods such as Luan et al. [28] considered both relevance and diversity of trips using maximal-marginal-relevance (MMR) and ant-colony-optimization (ACO), while more recent approaches like Luan et al. [29] proposed the FMSF model, which integrates a user’s preferences with similar users’ features and adopts an attention mechanism for multi-step future POI prediction, improving recommendation accuracy. Similarly, Sun et al. [30] proposed the MINet model, which leverages dynamic and static knowledge graphs to jointly model temporal preference evolution and multimodal semantic information, effectively capturing both time-dependent and stable user–POI relationships to enhance next POI recommendation performance. In addition to user behavioral modeling, accurate geographic localization also plays an essential role in POI recommendation, especially under noisy or missing GNSS signals in urban environments. For instance, Wang et al. [31] introduced a geometry-based cooperative localization method to improve positioning accuracy during temporary GNSS signal loss, which highlights the importance of reliable spatial modeling for location-aware recommendation systems. Similarly, in the field of cooperative control for connected and automated vehicles, to address the limitations of decentralized traditional solutions in complex traffic scenarios, Liang et al. [32] proposed a multi-agent system-based hierarchical control architecture. This architecture coordinates discrete behaviors and integrates motion control, thereby ensuring the safety and stability of vehicle platoons in real-time operation.
2.2. Recurrent-Neural-Network-Based Recommendation
Due to the advancements in deep learning, most existing methods treat user check-in records as sequential data and learn users’ interest preferences from check-in sequences using neural networks such as RNNs to recommend the next POI. Feng et al. proposed a PRME-G model [1], which models user preference sequences while aggregating location context information, personalized preferences, and geographic influence to accurately generate next POI recommendations. For example, Zhao et al. [11] introduced a Spatio-Temporal Gated Network (STGN) that incorporates time gates and distance gates into the LSTM architecture. This design separately controls users’ long-term and short-term interests and couples the input and forget gates to reduce the number of parameters, thereby improving model effectiveness. Additionally, Wu et al. [33] proposed a Personalized Long- and Short-Term Preference Learning (PLSPL) framework. Since POI locations and categories can reflect different aspects of user preference information, PLSPL models users’ personalized preferences and long-term POI recommendation mechanisms, enabling the learning of specific user preferences. Currently, to more accurately capture users’ preference habits from check-in sequences, attention mechanisms are widely adopted to allow the model to autonomously focus on salient feature information.
Although the aforementioned methods have achieved a certain degree of success, they still face challenges in addressing spatial sparsity and effectively modeling the temporal dynamics for the next POI recommendation. To address the issues, Luo et al. [14] proposed a spatio-temporal attention network (STAN). STAN uses a one-layer attention architecture to aggregate the correlation dependencies of non-adjacent POI locations, simultaneously using another layer of attention architecture to consider personalized preference frequency for discontinuous POI visits. The recall of POIs was achieved, and the next POI location recommendation was realized. However, such sequential models treat multi-dimensional heterogeneous spatio-temporal interactions as single numerical representations. By compressing interactive relationships into numerical values to construct spatio-temporal matrices, these methods lead to the loss of high-dimensional information such as semantic functional relationships and user social connections. Consequently, this limitation hinders further improvement in the accuracy of POI recommendation systems.
2.3. Hypergraph-Learning-Based Recommendation
Distinct from traditional recommendation systems, due to the need to consider various relationships between users and locations in POI recommendation, including geographical location relationships, user behavior relationships, social relationships, etc., graph networks can naturally represent and process these complex relationships and connections. In order to solve the problem of difficult prediction of users’ next location due to complex factors such as contextual information and personalized preferences, a new model of graphic enhancement transformer is proposed by Yang et al. [34]. The location or time signals of other users can be integrated into the converter model to accurately predict the user’s next POI location while also improving the cold start problem.
Recent studies have revealed that traditional graph structures, which only capture pairwise relationships between nodes, struggle to model higher-order interactions such as collaborative visits among multiple POIs. In contrast, methods based on Hypergraph Neural Networks (HGNNs) can capture complex high-order features and latent semantic information, thereby improving model performance. These advantages have drawn increasing attention to HGNNs in the field of POI recommendation. For example, Zhang et al. [35] proposed a Hypergraph Structure-based Aggregation Network (HS-AGN), which introduces a bidirectional aggregation mechanism via mutual attention to model high-order relationships in complex interactions, leading to improved recommendation performance. However, to construct more refined user profiles and achieve more personalized and accurate recommendations, it remains essential to integrate multi-modal data. To address this issue, Lai et al. proposed an Adaptive Spatio-Temporal Hypergraph Fusion Learning (ASTHL) framework for next POI recommendation [36]. This approach decouples spatial and temporal factors, incorporates contrastive learning, and leverages multi-modal features to enhance POI semantic information, effectively mitigating the mutual influence of spatio-temporal factors. These methods demonstrate the superiority of HGNNs in POI recommendation systems and indicate promising future directions.
It should be noted, however, that most existing hypergraph-based POI recommendation systems rely on single-layer hypergraphs to model user–POI relationships, which somewhat limits the modeling of high-dimensional relations. To tackle this problem, Zuo et al. [37] proposed a Global User Graph Enhanced Network (GUGEN), which constructs a multi-level hypergraph structure to explicitly model the semantic hierarchy of POIs. Although this method compresses redundant information through a global user graph, its computational efficiency still requires further improvement.
2.4. Attention-Mechanism-Based Recommendation
The attention mechanism [38] was initially inspired by cognitive science, designed to mimic the human ability to focus on important information when processing it. In the field of deep learning, the attention mechanism has become a key technology for handling complex tasks such as Natural Language Processing (NLP) and Computer Vision (CV). Compared to traditional sequence models like Recurrent Neural Networks (RNN) or Long Short-Term Memory Networks (LSTM), the attention mechanism is better at capturing long-range dependencies and effectively addressing issues such as gradient vanishing. For example, Feng et al. [39] proposed the ROTAN model, an innovative temporal encoding paradigm. Its core lies in the introduction of Time2Rotation technology, which embeds temporal information by representing time slots as rotation vectors and performing rotation operations. Based on this, ROTAN constructs a rotation-based temporal attention network aimed at collaboratively modeling asymmetric temporal influences in collaborative POI transition graphs and extracting time-aware user preferences and POI representations from individual trajectories. Similarly, Huang et al. [40] proposed a multi-attention-based group recommendation model (MAGRM) that employs attention networks to capture internal group social features and group-member preference interactions, achieving significant improvement in group recommendation tasks. Additionally, Huang et al. [41] introduced a multi-interaction graph attention network for bundle recommendation (MGBR), which leverages hierarchical graph attention and multi-task learning to model user–item and user–bundle interactions more effectively, demonstrating superior performance over previous methods.
Furthermore, the attention mechanism dynamically assigns weights to each input position, enabling flexible and selective focus on different parts of the source sequence, which significantly enhances model performance. For instance, Xu et al. [42] proposed the MobGT model to address the challenge of strong coupling between spatio-temporal information in graph neural networks, which makes it difficult to model them separately. The core of this model lies in a graph transformer architecture that employs separate encoders to extract purified spatio-temporal features and utilizes a graph attention mechanism to capture global user–location relationships. To mitigate data sparsity issues, the model also innovatively introduces tail loss, specifically designed to optimize performance under long-tailed distributions. Similarly, Zuo et al. [43] tackled the challenges of complex user mobility patterns and representation distribution biases by proposing the Diff–DGMN model, which attempts to introduce diffusion models into the POI recommendation field. This model constructs a dual-graph structure comprising a local transition graph and a global distance graph to capture sequential and geographical information separately, integrating them through an attention mechanism. Finally, the model leverages the forward and reverse generation processes of diffusion to sample from the posterior distribution for predicting user preferences, achieving significant performance improvements across multiple metrics.
The self-attention mechanism is a specialized form of attention mechanism that captures global dependencies within a sequence by dynamically weighting the relationships between each element and all other elements. This mechanism has become a core component of the Transformer architecture and has been widely adopted in next POI recommendation tasks due to its powerful sequence modeling capabilities. For instance, to simultaneously model long-term preferences and short-term context in user mobility behavior, Luo et al. [14] proposed the STAN model. This model employs a dual-Transformer encoder architecture: one encoder processes the user’s long-term historical trajectories to capture stable interest patterns, while the other focuses on recent short-term trajectories to perceive immediate intent. Finally, the model integrates long-term and short-term representations to achieve accurate next POI prediction.
As core technologies in deep learning, the attention mechanism and self-attention mechanism have substantially improved models’ capacity to handle long-range dependencies and global information. The attention mechanism dynamically assigns weights to different parts of the input sequence, enabling flexible focus on the most important features. In contrast, the self-attention mechanism further strengthens model expressiveness by facilitating global information interaction within the sequence. Currently, attention mechanisms are widely applied in natural language processing (NLP), image processing, and recommendation systems. In recommendation systems, the attention mechanism can capture long-range dependencies in users’ historical behaviors and dynamically adjust the importance weights of different historical actions, thereby improving the accuracy of recommendation results.
Following the success of large language models in natural language processing, their application has rapidly expanded to next point-of-interest recommendation tasks. In this direction, Li et al. [44] proposed the LLM4POI framework, which transforms the recommendation problem into a language modeling task through carefully designed trajectory prompts, thereby preserving the original semantics of the data and leveraging commonsense knowledge from pre-trained LLMs for reasoning. This method has achieved remarkable results in cold-start and short-trajectory scenarios, demonstrating the unique advantages of LLMs in semantic understanding and knowledge utilization, while our research shares a partially aligned objective with LLM4POI—both aiming to utilize contextual information more effectively, our MTFNR model adopts a distinct technical pathway. Instead of fully relying on the generative capabilities of LLMs, we focus on deeply integrating spatio-temporal gating mechanisms within an efficient GRU architecture, striving to achieve a better balance between performance and efficiency while ensuring practical applicability.
2.5. The Problem Definition
- The set of users is set to , and the set of POIs is set to , where the size of the set is represented as .
- The set of user u check-in sequences is defined as , where the user’s check-in sequence consists of chronologically sorted records. Each check-in record is represented by a four-tuple , where t denotes the check-in timestamp and specifies the geographic coordinates of location l.Since user check-in sequences exhibit variable lengths, we standardize them to a fixed length n. For sequences where , we retain only the n most recent check-ins and discard earlier records. For sequences where , we exclude the user from the dataset. This ensures sufficient data volume for model training, as inadequate data would limit learning capacity and compromise the model’s generalization ability and stability.
- The timestamp sequence and latitude-longitude sequence of the check-in sequence are represented by and , and the time interval and space interval between and from the are and , respectively, where is a function that computes the true distance between any two places on the earth.
- Assume that Point 1 has latitude and longitude and Point 2 has latitude and longitude , where denotes latitude and denotes longitude (both in radians). The intermediate variable a represents the computed value of the haversine function for the central angle between two points on the sphere, and d denotes the great-circle distance between the two points. The spherical distance between Point 1 and Point 2 is given by :where R represents the Earth’s radius, typically taken as R = 6371 km.
- Hypergraph neural network (HGNN) is defined as , where V represents the set of nodes, E represents the set of hyperedges. For each hyperedge , two or more nodes can be connected; that is represented by , and the weight diagonal matrix of hyperedges is represented by W.
- Based on the above definitions, the next POI recommendation problem can be defined as: given the check-in sequence from a specific user u, the goal is to predict the possible places that he goes by learning the user’s check-in sequence.
3. Proposed Method
The structure of the Multimodal Temporal Fusion for Next POI Recommendation (MTFNR) is illustrated in Figure 2. The model mainly consists of five modules: multi-modal embedding coding, time information modeling (TIHN), long- and short-term preferences modeling (LSTHN), spatio-temporal gate embedded GRU (STGRU), and the prediction component. Our main contribution lies in using HGNN to model users’ behavior patterns within a 24 h period and to learn users’ long- and short-term travel preferences, thereby dynamically capturing changes in user interests across different time periods.
Figure 2.
The Architecture of the MTFNR Model.
Furthermore, to enhance the adaptability and robustness of the recommendation system in handling spatio-temporal dynamics, we improved the GRU model by incorporating a gating mechanism with spatio-temporal embeddings. This design allows the model to explicitly perceive and integrate key contextual information, such as time intervals and geographical distances between locations, thereby more accurately capturing continuous dependencies in user movement behavior. Compared to the Transformer architecture, the GRU’s gating mechanism effectively captures short- to medium-range sequential dependencies while maintaining a more compact structure with fewer parameters. This not only improves training and inference efficiency but also reduces the risk of overfitting on medium-scale trajectory data, making it more suitable for modeling local continuity requirements in next-location recommendation tasks.
It is worth emphasizing that HGNN has clear advantages over conventional GNNs in the context of POI recommendation. HGNN can model higher-order relationships by integrating users, POIs, and time information into hyperedges, whereas traditional GNNs are limited to pairwise relationships, making HGNN more effective in capturing complex behavioral patterns. In addition, for cold-start users or sparse check-in data, HGNN can leverage hyperedges to associate behaviors of similar users or similar POIs, thereby improving the prediction of the user’s current interests. HGNN can also simultaneously capture behavior patterns at different temporal scales, which is crucial for understanding both short-term situational needs and long-term interest trends. For example, when a user has only a few past check-ins at certain entertainment venues, HGNN can associate this user with others who have similar preferences through hyperedges, allowing the model to predict likely POI visits in the current period. By combining HGNN with the enhanced GRU, the MTFNR model can effectively capture higher-order dependencies, temporal dynamics, and spatial continuity, resulting in improved overall recommendation performance.
3.1. Multi-Modal Embedding Coding
Rich information about human motion is usually included in the trajectory sequence. However, due to mobile device limitations or user behavior, trajectory sequences often exhibit high sparsity. In order to solve this problem, the sequence embedding method is used to process such data. In the process of modeling, the following three different types of attributes are mainly used: ID number of POI, time interval, and space interval. Different embedding methods are applied to these different attributes in check-in sequences.
For the ID attribute of POIs, we map it to a P-dimensional dense vector through a learnable embedding lookup table. The embeddings of all POIs collectively form the feature matrix , where N is the total number of POIs.
Aiming at the time interval and spatial interval between check-ins in the sequence, considering that in the preference model, too much space-time interval information may cause redundancy problems. Therefore, the time interval threshold and the spatial interval threshold are set to control it within a certain range, expressed as and . In order that the spatio-temporal relationship of users in the data be displayed intuitively, calculate the relative length of the time interval and the space interval in the user check-in sequence, as shown in Formula (3).
where represents the minimum time interval in the user u check-in sequence, and represents the minimum space interval in the user u check-in sequence. Meanwhile, in order to speed up the gradient descent to find the optimal solution and speed up the convergence of the training network, and are scaled to the range of [0, 1] by max-min normalization, as shown in Formula (4).
This normalization method allows the distribution shape of the original data to be preserved, and all features are scaled to the same range; it helps to avoid the impact of scale differences between features on model training.
For the time interval and spatial interval between consecutive check-ins, we first perform truncation and normalization to obtain standardized scalar values and . Subsequently, they are mapped to P-dimensional vectors and via independent embedding layers, respectively, to characterize the spatio-temporal context in the transition.
3.2. Time Information Modeling
POIs in real life often exhibit strong temporal characteristics, with some POIs showing varying levels of attractiveness and value during different time periods. To capture the correlations and sequential regularities among POIs over time, we construct a Time-Aware Hypergraph Network (TIHN). This network is designed to learn user behavior patterns across distinct time segments, enabling more precise prediction of users’ next POIs. By dividing the day into 24 time slots, the model can effectively capture temporal variations in user preferences—for example, a coffee shop may be more relevant in the morning, while a restaurant may be preferred in the evening. Such time-aware modeling not only improves the accuracy of POI recommendations but also enhances the user experience by providing contextually appropriate suggestions, demonstrating the practical value of incorporating temporal dynamics into the recommendation process.
The temporal information from user check-in sequences reflects time preferences in user behavior. We construct a temporal hypergraph where nodes represent POIs and hyperedges represent hourly time slots. The incidence matrix captures POI-time relationships, as shown in Formula (5).
where represents a POI node and represents a time hyperedge (e.g., for 1:00–2:00 a.m.).
To emphasize frequently visited time periods, we assign weights to hyperedges based on visit frequency. The hyperedge weight matrix is defined as shown in Formula (6).
where counts the total POI visits during an hour i, and m is the normalization factor.
Through hypergraph convolution, we aggregate temporal information and capture higher-order relationships. The l-th layer update is shown in Formula (7).
where and are degree matrices for nodes and hyperedges, respectively, and are learnable parameters. To ensure numerical stability, we apply with a small when necessary.
Multiple layers are stacked to capture information at different levels. The final time-aware POI representations are obtained by summing the outputs from all L layers, as shown in Formula (8).
This approach effectively models the temporal periodicity in user check-in behavior, providing enriched POI representations that incorporate time-dependent preferences.
3.3. Long- and Short-Term Preferences Modeling
To capture the evolution of user interests over time and improve recommendation timeliness, we construct multiple hypergraph neural networks to model user preferences at different temporal scales.
We first process the user’s check-in sequence to calculate the sequence intervals between POIs. The sequence interval matrix is defined in Formula (9).
where denotes the minimum sequence interval between POI and , and N is the total number of POIs visited. We only calculate intervals where was visited before to reflect actual behavior patterns and simplify analysis.
We then construct K hypergraph neural networks with different sequence spans , each with a corresponding weight (where ). Small spans capture short-term preferences (recent activities), while large spans model long-term behavioral trends. The optimal number of spans is determined experimentally in Section 5.2.
For each hypergraph , the incidence matrix captures relationships between POIs based on sequence intervals as shown in Formula (10).
where indicates that POI and are connected within the specified sequence span . When , it represents the sequence interval between a POI and another POI that is more than the sequence span that is set, or the user has not visited the other POI before visiting a POI.
The hyperedge weight matrix is defined based on POI visit frequencies, as shown in Formula (11).
where represents the visit frequency of POI , and m is a normalization factor.
Through hypergraph convolution, we aggregate multi-scale information. The update for layer l is shown in Formula (12).
where and are degree matrices, and are trainable parameters.
Multiple layers are stacked using sum-pooling to capture hierarchical information, as shown in Formula (13).
Finally, the outputs from all K hypergraphs are aggregated using learnable weights to obtain a comprehensive preference representation, as shown in Formula (14).
This representation effectively integrates both short- and long-term user preferences for improved POI recommendation.
3.4. Spatio-Temporal Gate Embedded GRU Model
The long-short term preferences of users and temporal information are closely interrelated. To integrate these aspects, we combine the POI representations learned from time information modeling () and long-short term preferences modeling () through a weighted sum, as shown in Formula (15).
where is an adjustable parameter that balances the influence of the two components.
Since users tend to visit POIs near their current location, we design T-shift and S-shift gates to incorporate transfer time and spatial distance information into the model. These gates address the GRU’s limitation in modeling nonlinear spatio-temporal relationships, as shown in Formula (16).
where , , , and are trainable weights, and are biases, and is the sigmoid function. The outputs and represent the influence of transfer time and space on the embeddings.
The spatio-temporal gated embedding is obtained by element-wise multiplication, as shown in Formula (17).
where ⊙ denotes element-wise multiplication.
This spatio-temporal enhanced embedding is then fed into the ST-shift-GRU unit, which extends the standard GRU with additional gates, as shown in Formula (18).
where R and Z are reset and update gates; is the candidate hidden state; and is the updated hidden state.
Multiple ST-shift-GRU units are stacked to form deep layers. For layer l, the computation is shown in Formula (19).
where denotes a single unit, and and encode spatial and temporal interval information.
The HGNN embeddings are projected into a unified latent space and fed as input features to the ST-shift-GRU. The outputs from the final layer are concatenated in Formula (20).
and linearly transformed to obtain the final output, as shown in Formula (21).
3.5. Next POI Prediction and Model Optimization
In order to estimate the user’s preference for the next visit to POI, the preference score of each candidate is calculated by the softmax function. The last node in is usually used as the estimation object, because this node aggregates the characteristics of all nodes. Supposed the timestamp of the last node of is t. When the timestamp is set as , POI location l preference score is as follows:
where represents the user’s preference at the timestamp t. By comparing the scores of all POIs, several POIs with higher scores are recommended to users.
After the user preference estimation is obtained, the cross-entropy loss function is used to optimize the objective function to prevent over-fitting and improve the generalization ability of the model by introducing L2 regularization (also known as weight decay). The loss function formula after introducing L2 regularization is as follows:
where is the predictive output of the model; is the regularization coefficient, and it is used to balance the weight of prediction and auxiliary loss function; and represents that all parameters are L2 regularized.
4. Experienments
4.1. Dataset
The experiments in this paper were conducted on three publicly available real-world datasets: Foursquare-NYC, Foursquare-TKY, and Gowalla. All datasets were collected from location-based social media platforms. The Foursquare-NYC and Foursquare-TKY datasets contain check-ins collected in New York City and Tokyo, spanning approximately 10 months (from 12 April 2012 to 16 February 2013). The Gowalla dataset was collected in California and Nevada, covering a longer time period and a wider geographic range. These datasets were chosen because they are publicly accessible, contain active users, have wide geographic coverage, and include temporal information, making them suitable for studying spatio-temporal behavior patterns in POI recommendation tasks while ensuring the reproducibility and scientific validity of the experiments.
The datasets include anonymized user IDs, POI location IDs with latitude and longitude information, POI category IDs, and check-in timestamps. In the preprocessing stage, we first filtered POIs and users: in the NYC and TKY datasets, POIs and users with fewer than 5 historical visits were removed, while in the Gowalla dataset, POIs and users with fewer than 10 historical visits were removed. All check-in records were then sorted chronologically to maintain the continuity of user behavior sequences. For feature engineering, POI geographic coordinates were normalized, and user historical behavior sequences were encoded by integrating the check-in time, location, and category information into the model input features. These preprocessing and feature construction steps reduce noise, unify feature scales, and help the model accurately capture users’ spatio-temporal behavior patterns, thereby improving the performance of next-POI prediction.
For dataset splitting, for each user with n check-ins, the first check-ins were used as training inputs, and the -th check-in POI was used as the training label. The check-ins were used as testing inputs, and the n-th check-in POI was used as the testing label. This time-continuous splitting approach simulates real-world next-POI prediction scenarios and ensures temporal consistency between training and testing data, providing a reliable basis for evaluating the model’s performance. The statistical results of the preprocessed datasets are summarized in Table 1.
Table 1.
Dataset statistics.
4.2. Baseline Model
- MF [4]: A commonly used method for solving recommendation problems, which learns the potential representations of users and POIs through matrix factorization.
- FPMC [33]: A method that combines matrix factorization (MF) with Markov chains, which introduces the Bayesian Personalized Ranking (BPR) framework to learn model parameters for recommendation.
- PRME [1]: A personalized ranking metric embedding method that integrates sequential information, personal preferences, and geographical influences.
- STGN [11]: A LSTM model that models the temporal and spatial intervals in check-in sequences, it use gate mechanisms to capture users’ long- and short-term preferences.
- PLSPL [34]: A model that combines users’ long- and short-term preferences through linear combination units.
- STAN [14]: An advanced model that learns patterns between non-adjacent locations and non-consecutive visits through a dual-layer attention architecture.
- GETNext [16]: A model that enhances next POI prediction using users’ unknown global trajectory flow graph and a novel graph-enhanced transformer.
- GUGEN [37]: A graph-enhanced model designed for next POI recommendation, which integrates information from both global and user-specific perspectives by constructing a global POI relation graph and individual user historical graphs.
- DisenPOI [21]: It is a point-of-interest recommendation model that utilizes sequential transitions and geographical proximity.
- MSTHN [45]: It is a location recommendation model that leverages spatial modeling advantages and temporal dynamics.
- STHGCN [46]: A model that proposes to capture high-order collaborative information between trajectories via a hypergraph structure, augmented by a novel hypergraph transformer to effectively fuse spatio-temporal context for enhanced next POI recommendation.
- DHCL [47]: A model that enhances bundle recommendation by leveraging dual hypergraphs to model high-order user–bundle interactions and optimizing representations through a bidirectional contrastive learning strategy.
4.3. Performance Metric
We evaluate our model using two standard metrics: Recall@k and NDCG@k.
Recall@k measures the proportion of relevant POIs captured in the top-k recommendations, as shown in Formula (24).
where is the number of users, denotes the top-k recommended POIs for user u, and represents the actual visited POIs.
NDCG@k evaluates the ranking quality by comparing the predicted ranking with an ideal ranking, as shown in Formula (25).
where (Discounted Cumulative Gain) measures the usefulness of the ranked list with penalties for lower positions, and (Ideal DCG) is the maximum possible achieved by perfect ranking, serving as the normalization factor.
We report results for and 10, averaging over multiple runs to reduce randomness.
4.4. Parameter Settings
The model was developed through the PyTorch 1.9.0 framework. The key hyperparameters and training settings of our model are listed below. The Adam optimizer uses the default beta value, and the learning rate is set at . The maximum length of the sequence was set to 100, and the sequence spans for modeling long- and short-term preferences were . Meanwhile, dropout was applied in the LSTHN, TIHN, and ST-GRU models. In the LSTHN and TIHN models, the dropout rate was set to 0.3, while in the ST-GRU model, it was set to 0.2. Additionally, in hyperparameter analysis, we analyzed the impact of key parameters such as POI embedding dimension, hypergraph neural network layers, and ST-GRU depth.
5. Results
5.1. Performance Comparison
We conducted experiments on three datasets to compare the performance of the MTFNR model with the baselines; the results for recall and NDCG@k () are obtained, as shown in Table 2 and Table 3.
Table 2.
Recall Performance comparison on three datasets.
Table 3.
NDCG Performance comparison on three datasets.
The table reveals that the MTFNR model outperforms the baseline models on all three datasets. Specifically, the MTFNR model achieves improvements of 2.32%, 15.46%, and 22.82% in Top-5 recall on the NYC, TKY, and GOW datasets, respectively. It also achieves improvements of 2.81%, 10.20%, and 15.97% in Top-10 recall on the same datasets. It achieves improvements of 0.97%, 5.19%, and 6.21% in NDCG@5 on the NYC, TKY, and GOW datasets, respectively. It also achieves improvements of 4.01%, 2.27%, and 3.22% in NDCG@10 on the same datasets.
The observed differences in improvement across datasets can be attributed to their varying levels of data sparsity and user behavior diversity. Specifically, the GOW dataset is significantly sparser than NYC and TKY, with fewer check-ins per user and higher POI diversity. Such sparsity makes it more challenging for conventional models to accurately capture user preferences. Our MTFNR model, which leverages multi-layer hypergraph networks (LSTHN and TIHN) and spatio-temporal gated recurrent units (ST-GRU), can effectively aggregate higher-order relations and temporal dependencies, thus achieving substantial gains on GOW and TKY. In contrast, the NYC dataset exhibits denser check-in patterns and more consistent user behaviors, where baseline models already perform competitively, leading to smaller relative improvements.
These results demonstrate the effectiveness of our proposed MTFNR model and the accuracy achieved through multimodal temporal information fusion. The performance improvement can be attributed to the following factors: (1) The MTFNR model utilizes hypergraph neural networks (HGNN) to obtain feature representations of POIs. Compared to traditional graph neural networks (GNN), HGNN aggregates node information through hyperedge connections. This process updates and propagates node features. This method can capture the multivariate and deep relationships between data more effectively, and enables the hypergraph to more naturally represent complex relationships in the real world. (2) Considering that user preferences may change over time, the MTFNR model incorporates both time information modeling (TIHN) and long- and short-term preferences modeling (LSTHN). The time information model captures user behavior patterns in different time periods; it provides a better understanding of user behavioral regularities. The long- and short-term preferences model dynamically captures changes in user interests; it enhances the timeliness of POI recommendations. (3) The MTFNR model incorporates the temporal and spatial interval information of user check-in sequences into the GRU model. It effectively captures the dependencies among the sequences. This consequently improves the robustness of the recommendation system and enhances the overall performance of the model.
In the baseline models, it can be observed that: (1) Deep learning-based methods such as STGN, PLSPL, and STAN outperform traditional methods like MF, FPMC, and PRME in terms of recommendation accuracy. This is because deep learning models can automatically learn and extract high-level features from the data. In POI recommendation, diverse data such as user geographical location, visit time, and historical behavior are involved. Meanwhile, deep learning can better capture complex patterns and correlations hidden behind the data. Recently proposed models such as DisenPOI further disentangle users’ sequential and geographical preferences, enabling deep learning methods to more precisely model different types of influence factors. (2) Graph network-based methods such as GETNext, GUGEN, STHGCN, DHCL and MTFNR outperform other deep learning-based methods (STGN, PLSPL, and STAN) in terms of recommendation accuracy. This is because graph networks can directly model the relationships between users and POIs. These relationships go beyond simple user behavior sequences. Furthermore, graph networks allow information propagation and aggregation throughout the entire graph structure, which enable better utilization of rich information within the network. This facilitates a better understanding of user interests and preferences, thereby improving the accuracy of recommendations. In addition, newly proposed graph/hypergraph-based models such as MSTHN integrate spatio-temporal features and high-order collaborative signals, further enhancing the modeling capability of graph-based approaches in complex relational scenarios.
We can also observe that the MTFNR model performs better in terms of improvement on the GOW dataset compared to the NYC and TKY datasets. This indicates that our model has a strong ability to learn from sparse data. Additionally, the MTFNR model achieves better improvement in Top-5 recall on the TKY and GOW datasets compared to Top-10 recall. This suggests that our model’s recommendations better align with user expectations and preferences. It leads to enhanced user satisfaction and experience.
5.2. Hyperparameter Analysis
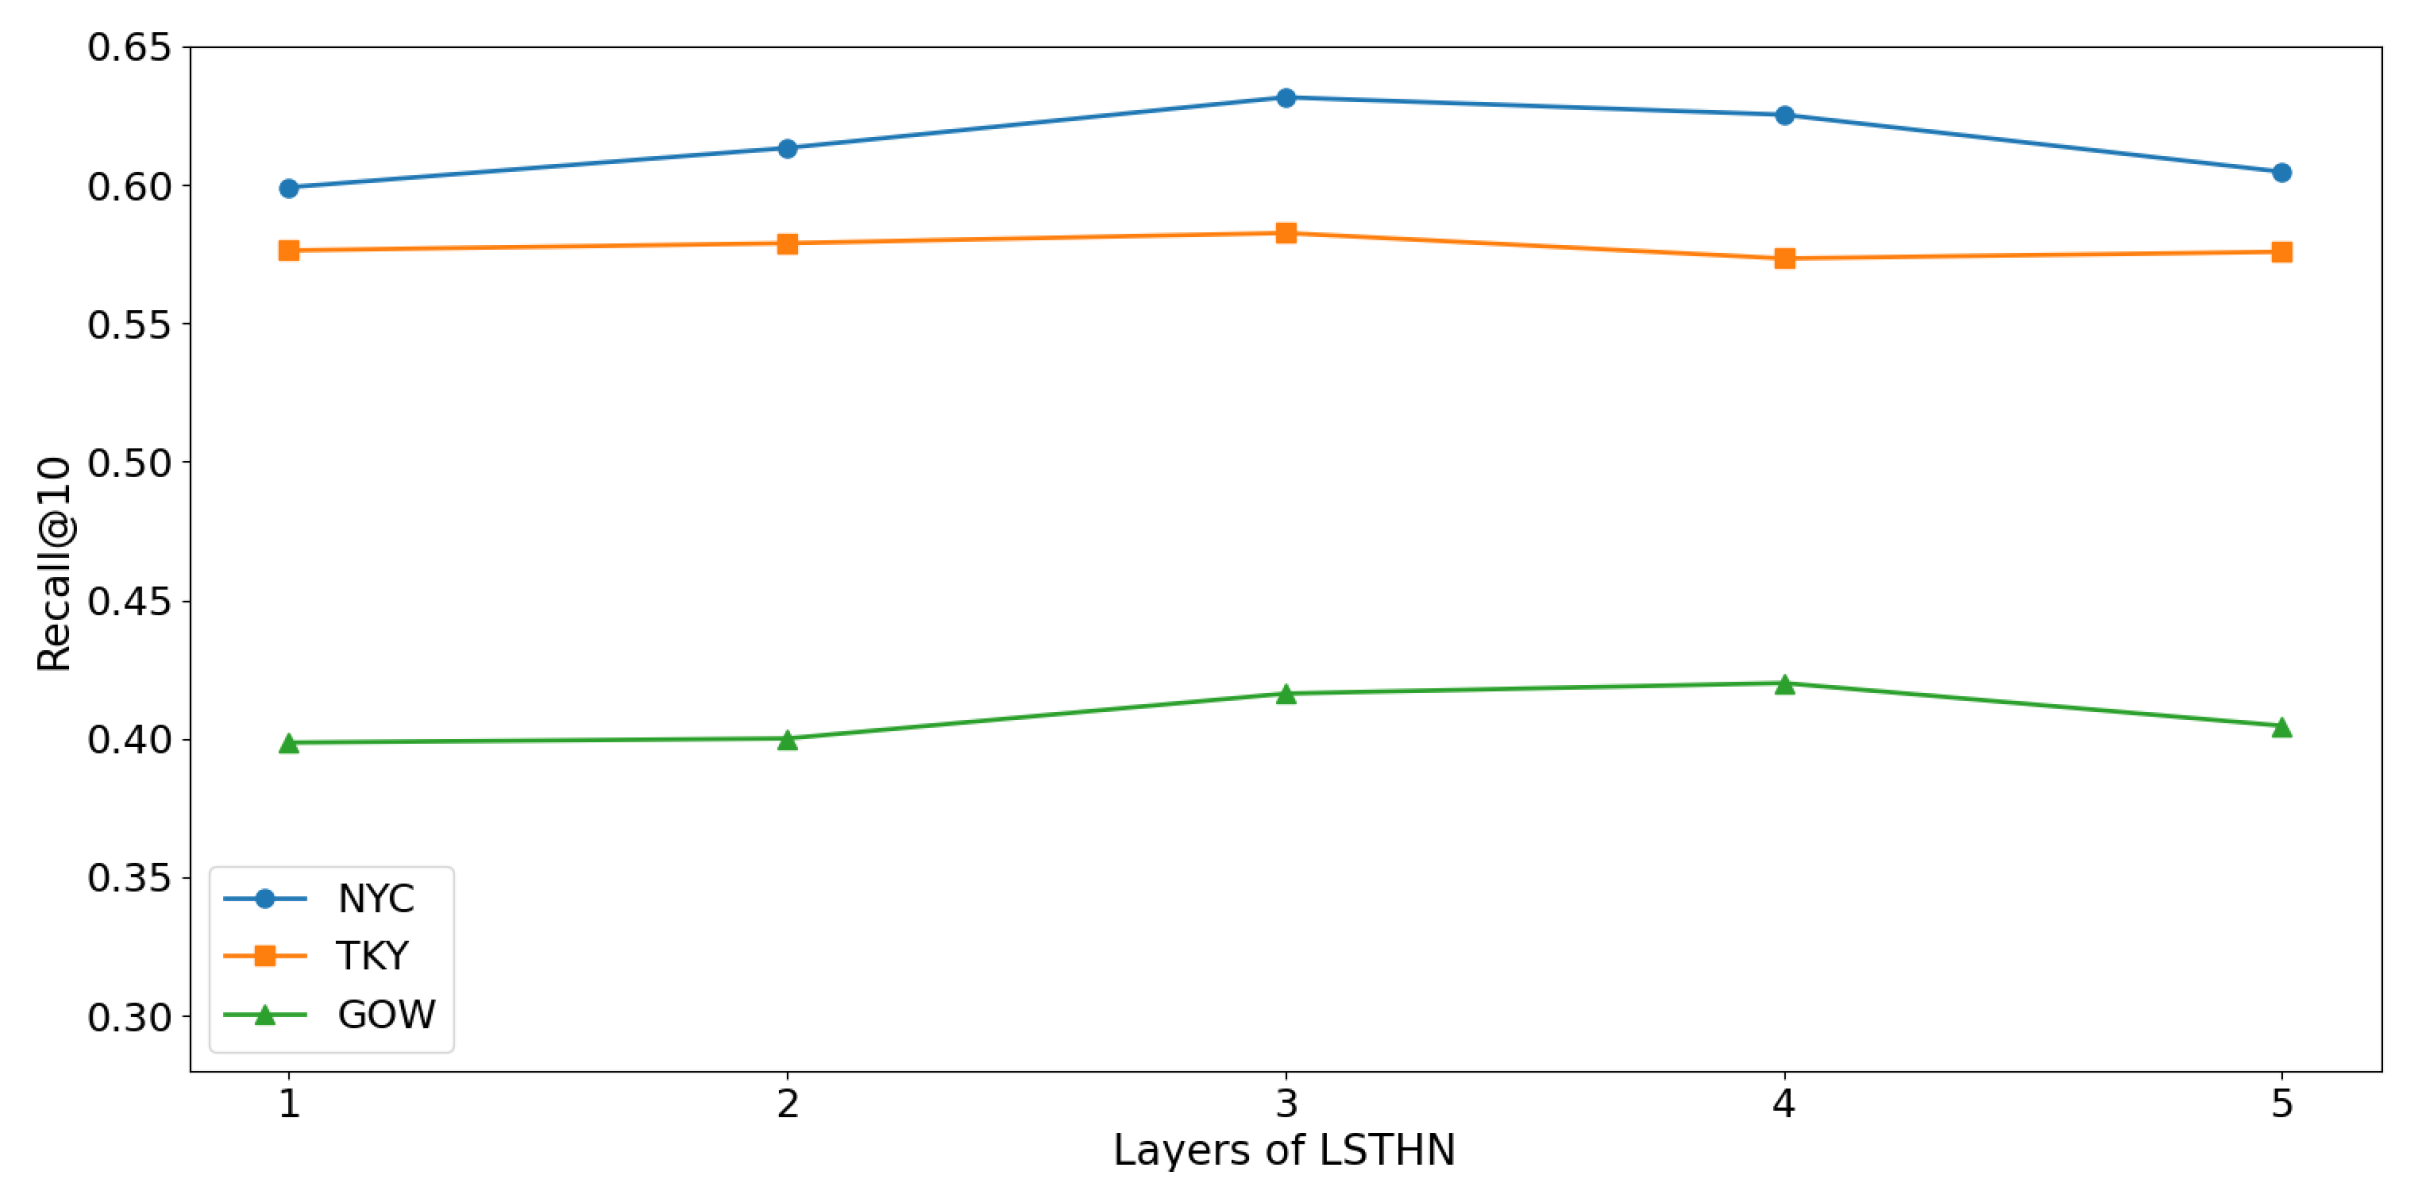
- The number of layers in LSTHNTo investigate the impact of the depth of LSTHN, this study varied the number of layers in the range of 1, 2, 3, 4, 5, as shown in Figure 3.The figure illustrates that as the number of layers in LSTHN increases, the accuracy of the model’s recommendations improves. This is because stacking more LSTHN layers helps capture complex correlations between POIs, thereby enhancing the model’s performance. However, when further increasing the number of LSTHN layers, the noise introduced by redundant stacking may lead to a decrease in model performance. And it also might result in only minor improvements in model performance, while these improvements require more computational resources and longer training time. Therefore, to balance model performance and resource requirements, we selected 3 layers of LSTHN for the NYC and TKY datasets and 4 layers of LSTHN for the GOW dataset.Figure 3. The numbers of layers in LSTHN.
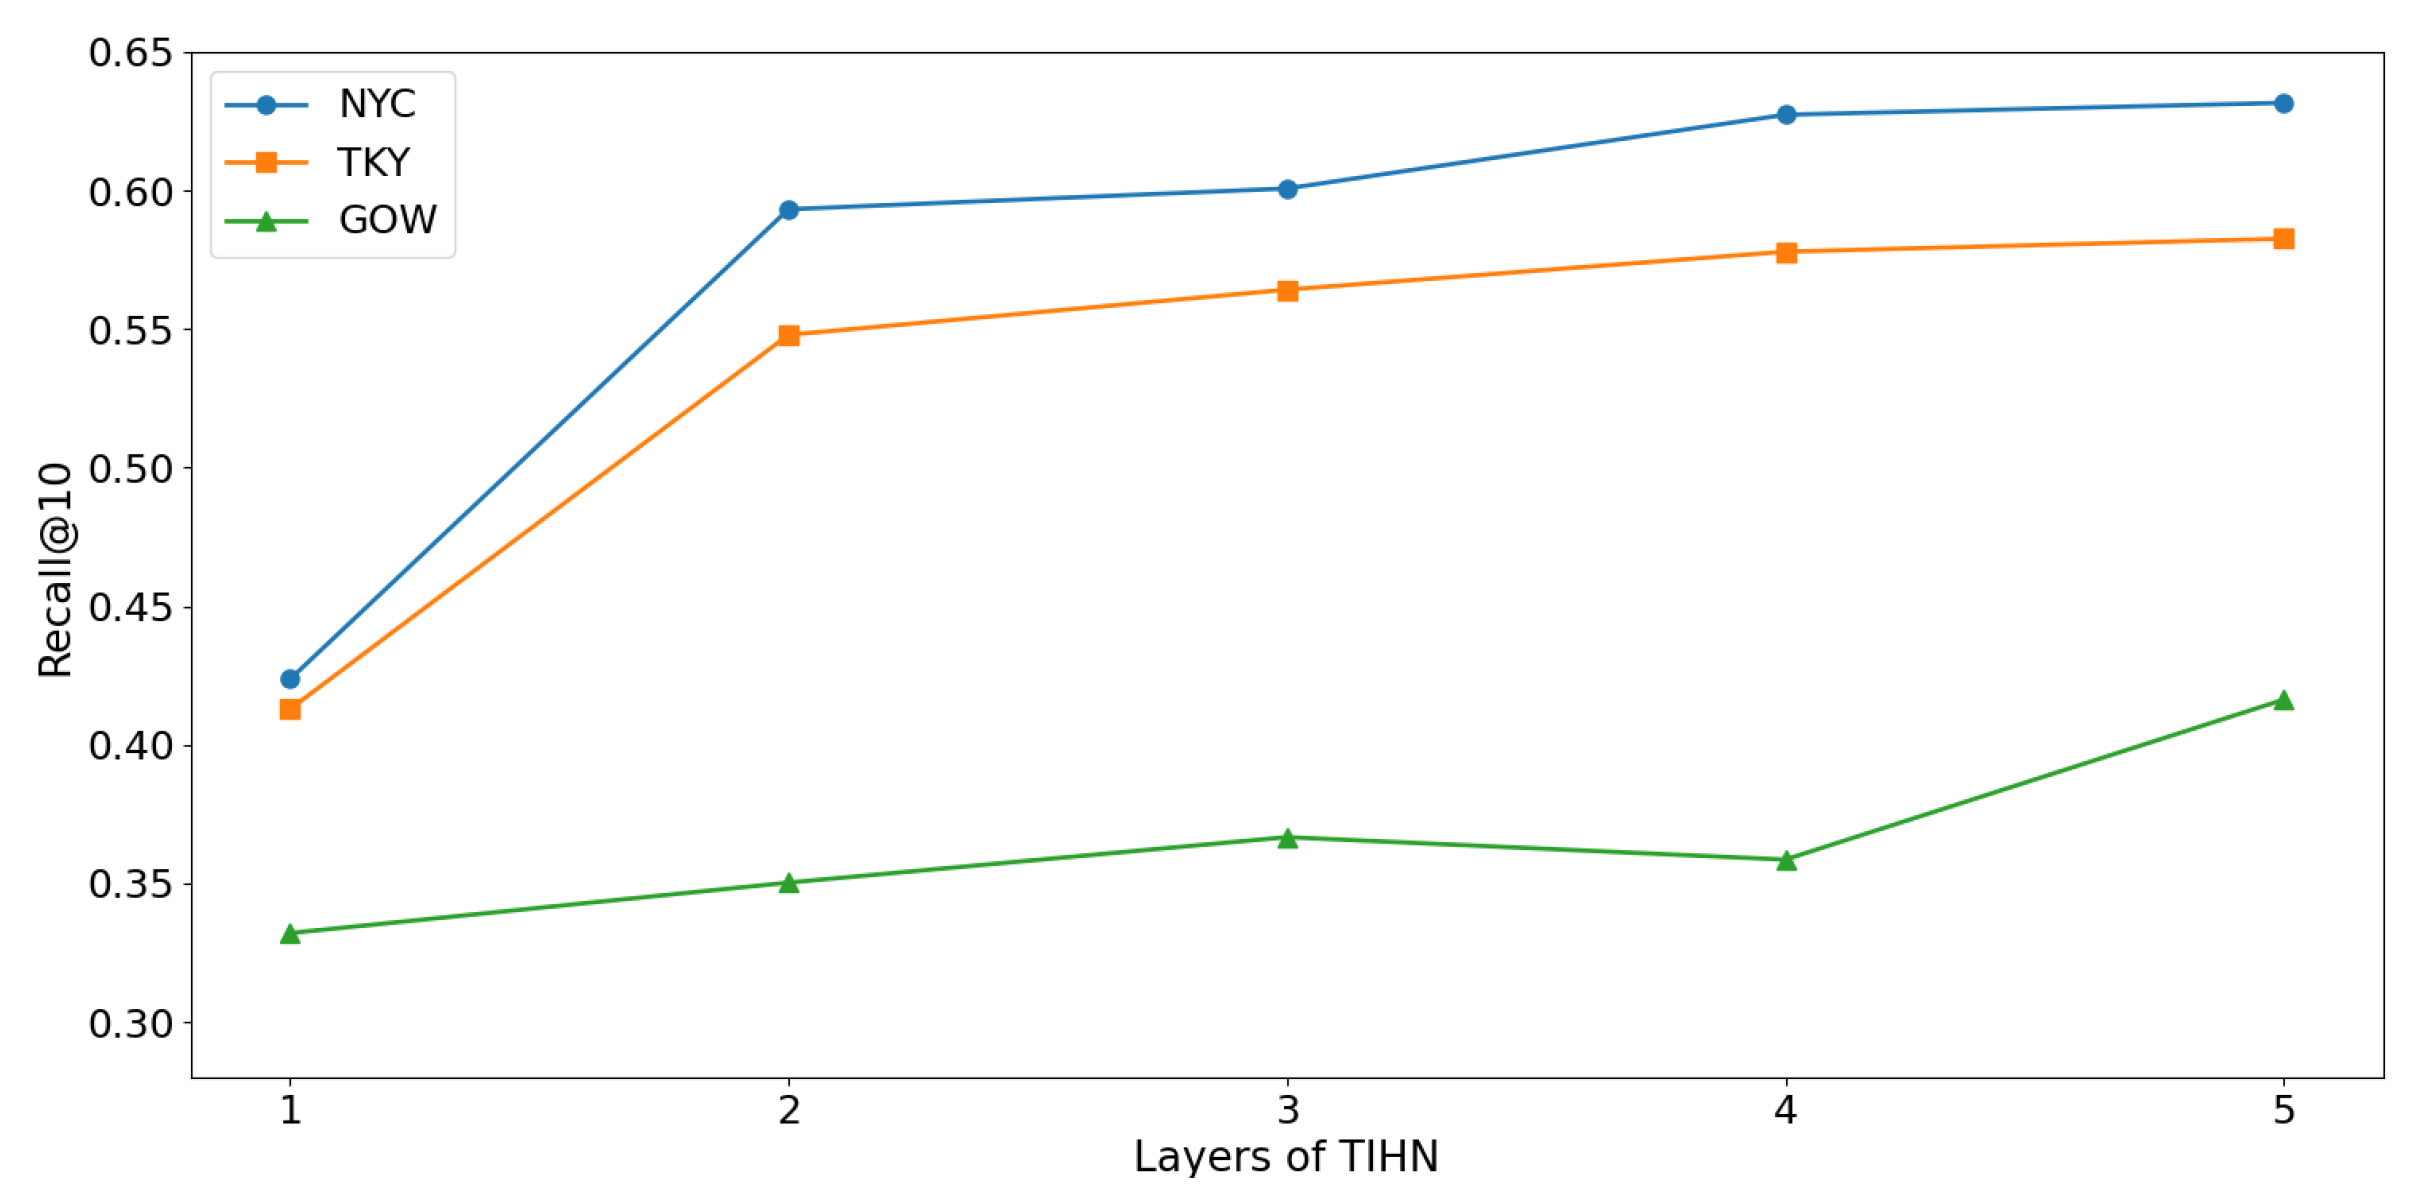
- The number of layers in TIHNTo investigate the impact of the depth of TIHN, this study varied the number of layers in the range of 1, 2, 3, 4, 5, as shown in Figure 4.The figure illustrates that as the number of layers in TIHN increases, the recommendation performance of the proposed method gradually improves. When the number of TIHN layers reaches 4, the recommendation performance is highest for the NYC and TKY datasets. When the number of TIHN layers reaches 5, the recommendation performance reaches its optimal state for the GOW dataset. This indicates that a lower number of TIHN layers is insufficient to aggregate enough neighbor information to enrich node representations, while a higher number of TIHN layers can better aggregate neighbor node information and improve recommendation performance. However, further increasing the number of TIHN layers may lead to a decline in recommendation performance. This could be attributed to the introduction of noise when the number of TIHN layers becomes too high, resulting in a decrease in recommendation performance. This also highlights the need for careful consideration when selecting the number of TIHN layers, as both excessively high or low numbers of layers can lead to a decline in recommendation performance.Figure 4. The numbers of layers in TIHN.
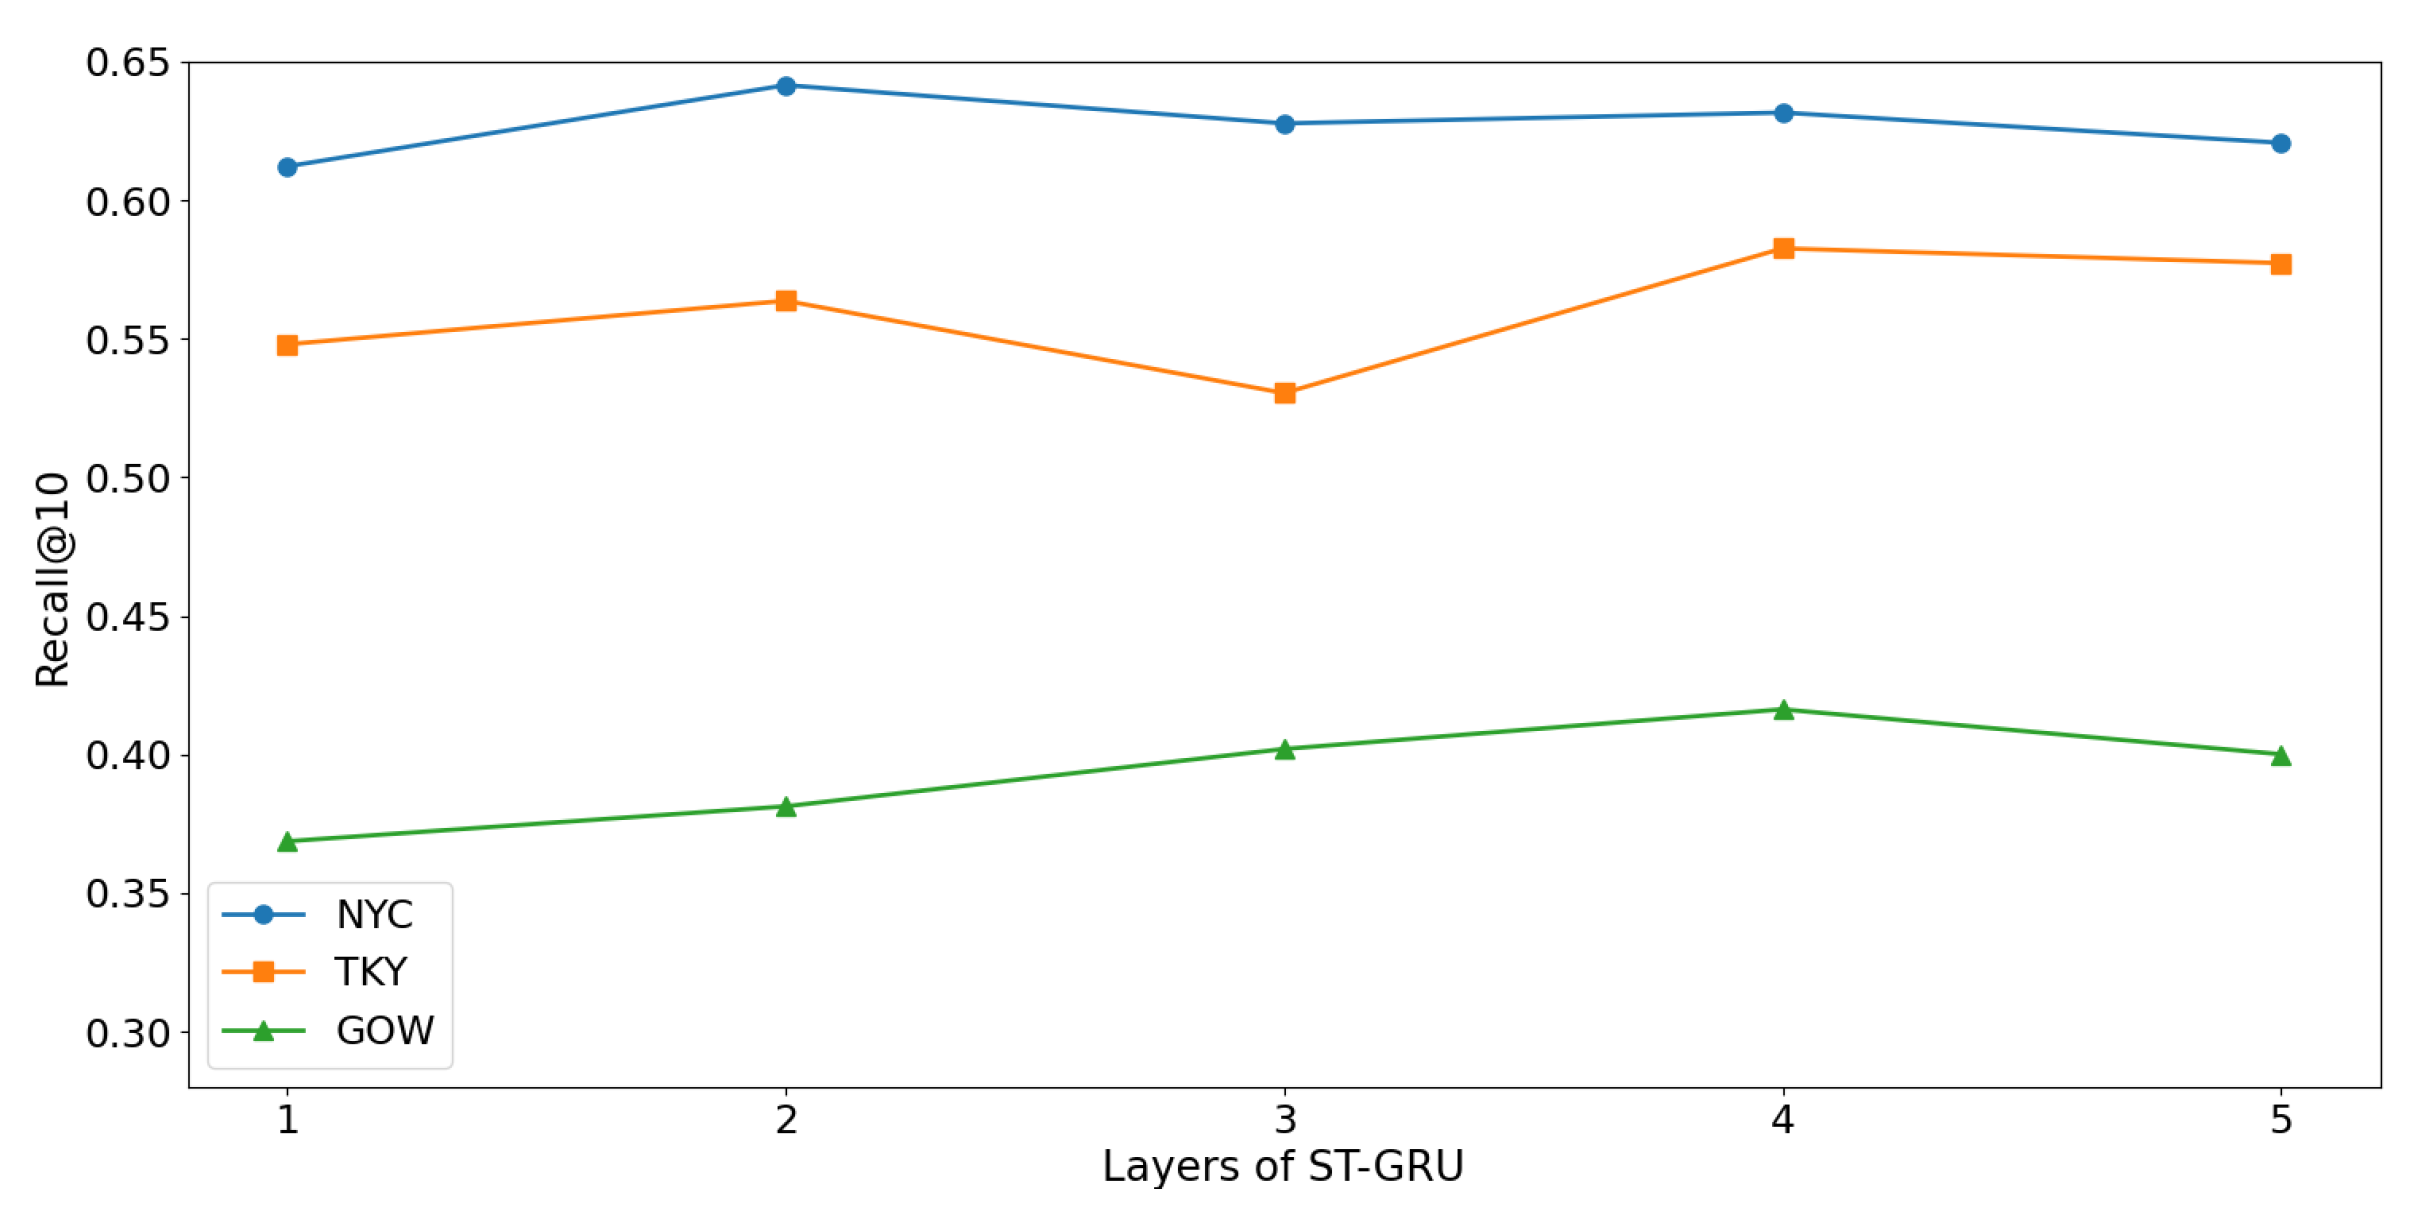
- The number of layers in ST-GRUTo investigate the impact of the depth of ST-GRU, this study varied the number of layers in the range of 1, 2, 3, 4, 5, as shown in Figure 5.The figure shows that ST-GRU achieves better recommendation performance when stacked with two layers on the NYC dataset, four layers on the TKY dataset, and four layers on the GOW dataset. The experimental results indicate that by stacking the layers of ST-GRU, it is possible to better fuse sequential features for recommendation. Recommendation performance can be influenced by multiple dimensions. So a low number of stacked ST-GRU layers may result in insufficient fusion of sequential features. However, increasing the number of stacked ST-GRU layers does not improve the recall rate of the model. This suggests that excessively stacking ST-GRU layers can lead to over-smoothing issues, which can affect the recommendation performance of the model.Figure 5. The numbers of layers in ST-GRU.
- POI Feature Embedding DimensionsTo investigate the impact of POI feature embedding dimensions, this study varied the size of POI feature dimensions within the range of 16, 32, 48, 64, 80 and conducted experiments on three independent datasets, as shown in Figure 6.Figure 6. The numbers of POI feature embedding dimensions.The figure shows that when the POI feature embedding dimension is set to P = 64, our model achieves optimal recommendation performance on the NYC, TKY, and GOW datasets. Specifically, the model’s recommendation accuracy initially increases with the gradual increase in POI feature embedding dimensions and then slightly decreases with further increases in dimensions. This is mainly because smaller dimensions of location embedding may limit the expression ability of the modeling. Although larger dimensions have better expressive power, they lead to a decrease in general performance and potential overfitting issues.
5.3. Sequence Interval Study
To demonstrate the effectiveness of modeling user long- and short-term preferences through local sequence intervals, the user’s long- and short-term preferences are modeled in the local sequence interval and the global sequence interval, respectively. The results are shown in Figure 7.
Figure 7.
Sequence interval results.
Local sequence intervals refer to when calculating the sequence intervals considering only the check-in information before a specific POI rather than considering the information after that POI. In contrast, global sequence intervals take into account all the check-in information available. The data in the figure demonstrates that modeling user long- and short-term preferences using local sequence intervals yields better results compared to using global sequence intervals across the three datasets. This is because local sequence intervals focus on a subset of check-in information, which makes the calculated sequence interval more dense and contain more useful information about user behavior. In contrast, global sequence intervals consider a larger amount of check-in information. It may lead to information sparsity and affect the accuracy of recommendations. Furthermore, global sequence intervals encompass all the check-in information. This may make recommendation results susceptible to noise and outliers. On the other hand, local sequence intervals only take into account recent check-in information. It allows for a better reflection of the user’s current interests and preferences, reduces the influence of noise, and improves the accuracy of recommendations.
5.4. Ablation Study
To validate the effectiveness of each variant in the MTFNR model, ablation experiments were conducted on the NYC, TKY, and GOW datasets, as shown in Figure 8 and Figure 9.
Figure 8.
Ablation (Recall@10) across datasets.
Figure 9.
Ablation (NDCG@10) across datasets.
The “w/o ST-GRU” variant removes the effects of time information modeling and user long- and short-term preferences modeling. This model’s impact solely is represented through random embedding encoding. The “w/o LSTHN” variant removes the influence of long- and short-term preferences modeling. This model considers only the impact of time information modeling. The “w/o TIHN” variant removes the impact of time information modeling; it focuses solely on long- and short-term preferences modeling.
From the results, the following can be observed:
- The “w/o LSTHN” and “w/o TIHN” variants show a certain decline in performance compared to the MTFNR model. This reveals that time information modeling and user long- and short-term preferences modeling have an impact on the model’s performance. So it is necessary to model adequately. Additionally, in the TKY dataset, the “w/o LSTHN” variant performs better than the “w/o TIHN” variant. But in the NYC and GOW datasets, the “w/o TIHN” variant outperforms the “w/o LSTHN” variant. This suggests that the importance of each component varies across different datasets.
- The “w/o ST-GRU” variant exhibits a significant drop in recommendation performance compared to other variants. This indicates that the user’s historical check-in sequence contains rich context information. The recommendation performance of the model can be improved by modeling time information through check-in timestamps and capturing user long- and short-term preferences through sequence intervals.
In addition, we investigated variants using only a single module, including w/TIHN, w/LSTHN, and w/ST-GRU, to analyze the independent contribution of each component. The results show that the model using only TIHN still achieves relatively strong performance across all datasets, indicating that time information modeling can effectively capture user behavior patterns. The model using w/LSTHN performs slightly worse than the TIHN-only model, suggesting that long- and short-term preferences modeling plays an important role in capturing user interests but is somewhat insufficient when used alone. The model using only ST-GRU performs noticeably worse than the previous two, yet still outperforms the random embedding baseline, demonstrating that the sequential modeling module can provide additional contextual information. Overall, these results indicate that the MTFNR model, by simultaneously modeling time information, long- and short-term user preferences, and sequential dependencies, can fully leverage multi-dimensional information to achieve the best recommendation performance across different datasets, while the contributions of individual components vary depending on the dataset, highlighting the effectiveness and flexibility of the model design.
ST-Shift is a gating mechanism that incorporates both spatial and temporal variations. Our ablation study, as shown in Figure 10, evaluates its components: w/o ST-Shift employs only the ST-Shift module, w/o T-Shift only the temporal (T-Shift) component, and w/o S-Shift only the spatial (S-Shift) component.
Figure 10.
Ablation study on ST-shift gating.
Based on the results the following can be stated: (1) Both the w/o T-Shift and w/o S-Shift variants show a clear performance drop compared to w/o ST-Shift, indicating that temporal and spatial gating are essential to model effectiveness; (2) Analysis of w/o T-Shift across datasets reveals that MTFNR enables better temporal flow of check-in information, demonstrating that long- and short-term preferences modeling and temporal modeling jointly enhance recommendations; (3) Furthermore, results from w/o S-Shift show that spatial flow of check-in information is also indispensable. Only by fully incorporating both temporal and spatial dimensions through ST-Shift can the model achieve strong performance.
5.5. Time Complexity Analysis
To evaluate the time efficiency of MTFNR, we conducted experiments on the Foursquare dataset with training ratios of 20%, 40%, 60%, 80%, and 100%. Figure 11 shows how the average training time per epoch changes with increasing data volume. MTFNR’s training time increases linearly from 39.71 s to 198.55 s, showing a similar growth rate to GETNext but consistently shorter than all four baselines. Specifically, with 20% data, MTFNR outperforms GETNext by 0.4 s, expanding to over 2 s with full data. Compared to the slowest baseline Diff-POI (275 s), MTFNR saves about 27.8% training time.
Figure 11.
Training time.
The stable linear growth demonstrates MTFNR’s scalability in both memory usage and computational complexity. This efficiency enables faster model iterations in practical applications, facilitating subsequent online tuning and deployment.
When the model is scaled to larger datasets, its computational complexity is primarily influenced by two factors. On the one hand, the structure of the hypergraph neural network is more complex than that of ordinary graphs. Since a hyperedge can connect multiple POI nodes simultaneously, the aggregation operation becomes computationally denser, and the computational cost of the hypergraph Laplacian matrix increases significantly. On the other hand, the GRU model has inherent limitations in processing long sequence data. Its sequential dependency nature restricts parallelization capability, making it difficult to fully utilize the large-scale parallel computing resources of GPUs. The time complexity of the module is shown in Table 4. The multi-layer hypergraph aggregation has a time complexity of , where denotes the number of edges in the graph and D represents the dimensionality of the node features. The GRU module has a time complexity of , where L is the sequence length, D is the input dimension, and H is the hidden dimension.
Table 4.
Time complexity analysis of each model.
To further analyze the computational efficiency of the proposed model, Table 4 summarizes the theoretical time complexity of the main baseline models. Compared with more complex models such as STHGCN and STAN, our model exhibits better scalability in terms of time complexity. Specifically, the time complexity of STHGCN is , which incurs high computational costs due to multi-head attention and hyperedge aggregation. STAN, based on self-attention, requires pairwise similarity computation among all check-ins, resulting in complexity that grows quadratically with trajectory length. STGN is based on LSTM with a time complexity of , and GETNext has a complexity of . In addition, Diff-POI introduces extra computation due to its diffusion sampling process and sequence graph encoder. Its sequence graph encoder has a complexity of , where n is the sequence length, and its geographic POI graph encoder has a complexity of , where denotes the number of edges in the geographic graph. Moreover, the diffusion sampling module requires T iterative steps, leading to a complexity of . Therefore, the overall time complexity of Diff-POI can be expressed as .
In contrast, our model consists of a multi-layer hypergraph aggregation module and a GRU module, whose complexities grow linearly with the number of edges and sequence length, respectively. This design effectively reduces the overall computational burden while maintaining strong representational capability. Therefore, our model achieves better scalability and training efficiency on large-scale datasets, striking a desirable balance between model performance and computational complexity.
Among them, in the time complexity expression for multi-layer hypergraph aggregation; denotes the number of hyperedges; D represents the dimensionality of each node’s feature vector; M denotes the number of hypergraph scales; K denotes the number of stacked hypergraph convolutional layers in HGNN; and is the total number of nodes. Secondly, in the time complexity expression for the GRU model, L is the length of the sequence, D is the dimensionality of the input layer, and H is the dimensionality of the hidden layer. Within a single GRU cell, a D-dimensional input vector is transformed via weight matrices, involving computations on matrices of size .
The complexity analysis in this study reveals the scalability challenges faced by the model when applied to large datasets. To address these challenges, we plan to implement targeted optimizations in future work. For hypergraph computation, we aim to optimize the multi-layer hypergraph aggregation module through graph sampling techniques (e.g., node sampling and layer sampling) or approximate graph convolution methods. In terms of sequence modeling, we will explore the introduction of hierarchical attention mechanisms or segmented processing of long sequences to significantly reduce computational complexity.
6. Conclusions
In order to promptly capture changes in user interests and provide users with more accurate POI recommendations, we propose a Multimodal Temporal Information Fusion for Next POI Recommendation (MTFNR) model. MTFNR uses time information and long- and short-term preferences fusion modeling to obtain users’ preference habits at different times and combines other feature information to improve the accuracy of recommendations. The MTFNR model captures users’ preference habits at different periods by modeling temporal information and fusing long- and short-term preferences while incorporating other feature information to improve recommendation accuracy. We conducted baseline experiments, ablation experiments, and hyperparameter experiments on three real-world datasets. The experimental results show that the recommendation accuracy of the MTFNR model is higher than that of variant models formed by removing different components, demonstrating the effectiveness of MTFNR in modeling temporal information and long- and short-term preferences. The MTFNR model consistently outperforms all baseline models across multiple core evaluation metrics. Specifically, in terms of recall, MTFNR achieves improvements of 2.32–22.82% in Recall@5 and 2.81–15.97% in Recall@10 compared to the current state-of-the-art model. Simultaneously, the model demonstrates significant progress in recommendation list quality and ranking accuracy, with NDCG@5 and NDCG@10 increasing by 0.97–6.21% and 2.27–10.07%, respectively. These results collectively demonstrate the superiority of the proposed MTFNR model over state-of-the-art methods.
In terms of spatio-temporal context modeling, future work will focus on achieving finer-grained analysis. From a temporal perspective, we will extend beyond the current modeling of periodicity and continuity to distinguish between weekday and weekend patterns and further investigate the specific impacts of special dates, such as holidays and large-scale events, on user movement behavior. Spatially, we plan to incorporate real road network data and geospatial semantic information (e.g., different urban functional zones) to transcend the limitations of Euclidean distance and more accurately quantify the practical accessibility and semantic relevance between locations.
Author Contributions
Conceptualization, methodology, F.L., J.L. and T.L.; data processing, coding, J.L.; validation, J.L. and T.L.; writing—original draft preparation, writing—review and editing, J.L. and T.L. All authors have read and agreed to the published version of the manuscript.
Funding
This work is supported in part by the National Natural Science Foundation of China (Grant No. 61971291), the Basic Scientific Research Project of the Liaoning Provincial Department of Education (LJ212410144013), the Leading Talent of the ‘Xing Liao Ying Cai Plan’ (XLYC2202013), the Shenyang Natural Science Foundation (22-315-6-10), and the Guangxuan Scholar of Shenyang Ligong University (SYLUGXXZ202205).
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
Due to the nature of this research, participants of this paper did not agree for their data to be shared publicly, so supporting data are not available.
Acknowledgments
We would like to express our gratitude to all colleagues and supporters who provided assistance during the writing of this paper. Special thanks are extended to Tianrui Li for their contributions to this work. They offered valuable suggestions throughout the writing process, which significantly helped improve the quality of the paper. We sincerely appreciate their selfless dedication and professional expertise, which were crucial factors in the successful completion of this research.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Feng, S.; Li, X.; Zeng, Y.; Cong, G.; Chee, Y.M.; Yuan, Q. Personalized Ranking Metric Embedding for Next New POI Recommendation. In Proceedings of the Twenty-Fourth International Joint Conference on Artificial Intelligence (IJCAI 2015), Buenos Aires, Argentina, 25–31 July 2015; pp. 2069–2075. [Google Scholar]
- Wang, D.; Wan, F.; Yu, D.; Shen, Y.; Xiang, Z.; Xu, Y. Context-and category-aware double self-attention model for next POI recommendation. Appl. Intell. 2023, 53, 18355–18380. [Google Scholar] [CrossRef] [Scilit]
- Jiang, S.; Qian, X.; Shen, J.; Fu, Y. Author Topic Model-Based Collaborative Filtering for Personalized POI Recommendations. IEEE Trans. Multimed. 2015, 17, 907–918. [Google Scholar] [CrossRef] [Scilit]
- Koren, Y.; Bell, R.; Volinsky, C. Matrix Factorization Techniques for Recommender Systems. Computer 2009, 42, 30–37. [Google Scholar] [CrossRef] [Scilit]
- Cheng, C.; Yang, H.; Lyu, M.R.; King, I. Where You Like to Go Next: Successive Point-of-Interest Recommendation. In Proceedings of the International Joint Conference on Artificial Intelligence, Beijing, China, 3–9 August 2013. [Google Scholar]
- Zhang, J.D.; Chow, C.Y.; Li, Y. Lore: Exploiting sequential influence for location recommendations. In Proceedings of the ACM SIGSPATIAL International Conference on Advances in Geographic Information Systems, Dallas TX, USA, 4–7 November 2014. [Google Scholar]
- Ching, W.K.; Ng, M.K. Markov Chains: Models, Algorithms and Applications, 2nd ed.; Springer Science & Business Media: New York, NY, USA, 2006. [Google Scholar]
- He, J.; Li, X.; Liao, L.; Song, D.; Cheung, W.K. Inferring a Personalized Next Point-of-Interest Recommendation Model with Latent Behavior Patterns. In Proceedings of the AAAI Conference on Artificial Intelligence, Phoenix, AZ, USA, 12–17 February 2016. [Google Scholar]
- Zhao, S.; Zhao, T.; Yang, H.; Lyu, M.R.; King, I. STELLAR: Spatial-Temporal Latent Ranking for Successive Point-of-Interest Recommendation. In Proceedings of the Thirtieth AAAI Conference on Artificial Intelligence (AAAI 2016), Phoenix, AZ, USA, 12–17 February 2016; pp. 315–321. [Google Scholar]
- Zeng, J.; He, X.; Tang, H.; Wen, J. Predicting the next location: A self-attention and recurrent neural network model with temporal context. Trans. Emerg. Telecommun. Technol. 2021, 32, e3898. [Google Scholar] [CrossRef] [Scilit]
- Zhao, P.; Luo, A.; Liu, Y.; Zhuang, F.; Zhou, X. Where to Go Next: A Spatio-Temporal Gated Network for Next POI Recommendation. IEEE Trans. Knowl. Data Eng. 2020, 34, 2512–2524. [Google Scholar] [CrossRef] [Scilit]
- Guo, Q.; Sun, Z.; Zhang, J.; Theng, Y.L. An Attentional Recurrent Neural Network for Personalized Next Location Recommendation. Proc. AAAI Conf. Artif. Intell. 2020, 34, 83–90. [Google Scholar] [CrossRef] [Scilit]
- Lian, D.; Wu, Y.; Ge, Y.; Xie, X.; Chen, E. Geography-Aware Sequential Location Recommendation. In Proceedings of the 26th ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD 2020), San Diego, CA, USA, 6–10 July 2020; pp. 2009–2017. [Google Scholar]
- Luo, Y.; Liu, Q.; Liu, Z. STAN: Spatio-Temporal Attention Network for Next Location Recommendation. In Proceedings of the WWW ’21: The Web Conference 2021, Ljubljana, Slovenia, 19–23 April 2021. [Google Scholar]
- Lim, N.; Hooi, B.; Ng, S.K.; Wang, X.; Varadarajan, J. STP-UDGAT: Spatial-Temporal-Preference User Dimensional Graph Attention Network for Next POI Recommendation. In Proceedings of the CIKM ’20: The 29th ACM International Conference on Information and Knowledge Management, Virtual, 19–23 October 2020. [Google Scholar]
- Yang, S.; Liu, J.; Zhao, K. GETNext: Trajectory flow map enhanced transformer for next POI recommendation. In Proceedings of the 45th International ACM SIGIR Conference on Research and Development in Information Retrieval, Madrid, Spain, 11–15 July 2022; pp. 1144–1153. [Google Scholar]
- Ye, Z.; Zhang, X.; Chen, X.; Xiong, H.; Yu, D. Adaptive Clustering Based Personalized Federated Learning Framework for Next POI Recommendation with Location Noise. IEEE Trans. Autom. Control 2024, 36, 14. [Google Scholar] [CrossRef] [Scilit]
- Gavalas, D.; Konstantopoulos, C.; Mastakas, K.; Pantziou, G.; Vathis, N. Heuristics for the time dependent team orienteering problem: Application to tourist route planning. Comput. Oper. Res. 2015, 62, 36–50. [Google Scholar] [CrossRef] [Scilit]
- Liu, Q.; Wu, S.; Wang, L.; Tan, T. Predicting the Next Location: A Recurrent Model with Spatial and Temporal Contexts. In Proceedings of the Thirtieth AAAI Conference on Artificial Intelligence (AAAI-16), Phoenix, AZ, USA, 12–17 February 2016; pp. 194–199. [Google Scholar]
- Wang, Z.; Zhu, Y.; Liu, H.; Wang, C. Learning graph-based disentangled representations for next POI recommendation. In Proceedings of the 45th International ACM SIGIR Conference on Research and Development in Information Retrieval, Madrid, Spain, 11–15 July 2022; pp. 1154–1163. [Google Scholar]
- Qin, Y.; Wang, Y.; Sun, F.; Ju, W.; Hou, X.; Wang, Z.; Cheng, J.; Lei, J.; Zhang, M. DisenPOI: Disentangling sequential and geographical influence for point-of-interest recommendation. In Proceedings of the Sixteenth ACM International Conference on Web Search and Data Mining, Singapore, 27 February–3 March 2023; pp. 508–516. [Google Scholar]
- Xie, M.; Yin, H.; Wang, H.; Xu, F.; Chen, W.; Wang, S. Learning graph-based poi embedding for location-based recommendation. In Proceedings of the 25th ACM International Conference on Information and Knowledge Management, Indianapolis, IN, USA, 24–28 October 2016; pp. 15–24. [Google Scholar]
- Meng, L.; Liu, Z.; Chu, D.; Sheng, Q.Z.; Yu, J.; Song, X. POI recommendation for occasional groups based on hybrid graph neural networks. Expert Syst. Appl. 2024, 237, 121583. [Google Scholar] [CrossRef] [Scilit]
- Fang, J.; Meng, X. URPI-GRU: An approach of next POI recommendation based on user relationship and preference information. Knowl.-Based Syst. 2022, 256, 109848. [Google Scholar] [CrossRef] [Scilit]
- Hao, P.Y.; Cheang, W.H.; Chiang, J.H. Real-time event embedding for POI recommendation. Neurocomputing 2019, 349, 1–11. [Google Scholar] [CrossRef] [Scilit]
- Liu, Y.; Pei, A.; Wang, F.; Yang, Y.; Zhang, X.; Wang, H.; Dai, H.; Qi, L.; Ma, R. An attention-based category-aware GRU model for the next POI recommendation. Int. J. Intell. Syst. 2021, 36, 3174–3189. [Google Scholar] [CrossRef] [Scilit]
- Ye, J.; Zhu, Z.; Cheng, H. What’s your next move: User activity prediction in location-based social networks. In Proceedings of the 2013 SIAM International Conference on Data Mining, Austin, TX, USA, 2–4 May 2013; pp. 171–179. [Google Scholar]
- Luan, W.; Liu, G.; Jiang, C.; Zhou, M. MPTR: A Maximal-Marginal-Relevance-Based Personalized Trip Recommendation Method. IEEE Trans. Intell. Transp. Syst. 2018, 19, 3461–3474. [Google Scholar] [CrossRef] [Scilit]
- Luan, W.; Feng, Z.; Qi, L.; Lu, X.S. FMSF: Future-preference Modeling with Similar-user Features for Next POI Recommendation. Neurocomputing 2025, 656, 131511. [Google Scholar] [CrossRef] [Scilit]
- Sun, X.; Gao, Z.; Yu, D.; Huang, B. Joint Modeling of Multimodal Information Based on Dynamic and Static Knowledge Graphs for Next POI Recommendation. IEEE Trans. Comput. Soc. Syst. 2025, 12, 3985–3999. [Google Scholar] [CrossRef] [Scilit]
- Wang, F.; Xu, L.; Zhuang, W.; Yin, G.; Pi, D.; Liang, J.; Liu, Y.; Lu, Y. Geometry-Based Cooperative Localization for Connected Vehicle Subject to Temporary Loss of GNSS Signals. IEEE Sens. J. 2021, 21, 23527–23536. [Google Scholar] [CrossRef] [Scilit]
- Liang, J.; Li, Y.; Yin, G.; Xu, L.; Lu, Y.; Feng, J.; Shen, T.; Cai, G. A MAS-Based Hierarchical Architecture for the Cooperation Control of Connected and Automated Vehicles. IEEE Trans. Veh. Technol. 2023, 72, 1559–1573. [Google Scholar] [CrossRef] [Scilit]
- Rendle, S.; Freudenthaler, C.; Schmidt-Thieme, L. Factorizing personalized markov chains for next-basket recommendation. In Proceedings of the 19th International Conference on World Wide Web, Raleigh, NC, USA, 26–30 April 2010; pp. 811–820. [Google Scholar]
- Wu, Y.; Li, K.; Zhao, G.; Qian, X. Personalized long-and short-term preference learning for next POI recommendation. IEEE Trans. Knowl. Data Eng. 2020, 34, 1944–1957. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Z.; Chen, J.; Zhao, X.; Gong, Y.; Ren, J.; Ouyang, J. A Hypergraph Structure-Based Aggregation Network for Next POI Recommendation. IEEE Access 2024, 12, 164878–164890. [Google Scholar] [CrossRef] [Scilit]
- Lai, Y.; Su, Y.; Wei, L.; Wang, T.; Zha, D.; Wang, X. Adaptive Spatial-Temporal Hypergraph Fusion Learning for Next POI Recommendation. In Proceedings of the ICASSP 2024—2024 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), Seoul, Republic of Korea, 14–19 April 2024; pp. 7320–7324. [Google Scholar]
- Zuo, C.; Zhang, X.; Yan, L.; Zhang, Z. GUGEN: Global User Graph Enhanced Network for Next POI Recommendation. IEEE Trans. Mob. Comput. 2024, 23, 14975–14986. [Google Scholar] [CrossRef] [Scilit]
- Niu, Z.; Zhong, G.; Yu, H. A review on the attention mechanism of deep learning. Neurocomputing 2021, 452, 48–62. [Google Scholar] [CrossRef] [Scilit]
- Feng, S.; Meng, F.; Chen, L.; Shang, S.; Ong, Y.S. ROTAN: A Rotation-based Temporal Attention Network for Time-Specific Next POI Recommendation. In Proceedings of the 30th ACM SIGKDD Conference on Knowledge Discovery and Data Mining, Barcelona, Spain, 25–29 August 2024; pp. 759–770. [Google Scholar]
- Huang, Z.; Xu, X.; Zhu, H.; Zhou, M. An Efficient Group Recommendation Model with Multiattention-Based Neural Networks. IEEE Trans. Neural Netw. Learn. Syst. 2020, 31, 4461–4474. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Huang, Z.; Guan, C.; Han, P.; Jia, Z. A Multi-interaction Graph Attention Network for Bundle Recommendation. In Service Science; Springer Nature: Singapore, 2025; pp. 49–63. [Google Scholar]
- Xu, X.; Suzumura, T.; Yong, J.; Hanai, M.; Yang, C.; Kanezashi, H.; Jiang, R.; Fukushima, S. Revisiting Mobility Modeling with Graph: A Graph Transformer Model for Next Point-of-Interest Recommendation. In Proceedings of the 31st ACM International Conference on Advances in Geographic Information Systems, Hamburg, Germany, 13–16 November 2023; pp. 1–10. [Google Scholar]
- Zuo, J.; Zhang, Y. Diff-DGMN: A Diffusion-Based Dual Graph Multiattention Network for POI Recommendation. IEEE Internet Things J. 2024, 11, 38393–38409. [Google Scholar] [CrossRef] [Scilit]
- Li, P.; de Rijke, M.; Xue, H.; Ao, S.; Song, Y.; Salim, F.D. Large Language Models for Next Point-of-Interest Recommendation. In Proceedings of the 47th International ACM SIGIR Conference on Research and Development in Information Retrieval, Washington, DC, USA, 14–18 July 2024; pp. 1463–1472. [Google Scholar]
- Lai, Y.; Su, Y.; Wei, L.; Chen, G.; Wang, T.; Zha, D. Multi-view Spatial-Temporal Enhanced Hypergraph Network for Next POI Recommendation. In Database Systems for Advanced Applications; Wang, X., Sapino, M.L., Han, W.-S., El Abbadi, A., Dobbie, G., Feng, Z., Shao, Y., Yin, H., Eds.; Springer Nature: Cham, Switzerland, 2023; pp. 237–252. [Google Scholar]
- Wang, J.; Wang, W.; Yu, W.; Liu, X.; Jia, K.; Li, X.; Zhong, M.; Sun, Y.; Xu, Y. STHGCN: A spatiotemporal prediction framework based on higher-order graph convolution networks. Knowl.-Based Syst. 2022, 258, 109985. [Google Scholar] [CrossRef] [Scilit]
- Zhang, P.; Niu, Z.; Ma, R.; Zhang, F. DHCL-BR: Dual Hypergraph Contrastive Learning for Bundle Recommendation. Comput. J. 2024, 67, 2906–2919. [Google Scholar] [CrossRef] [Scilit]
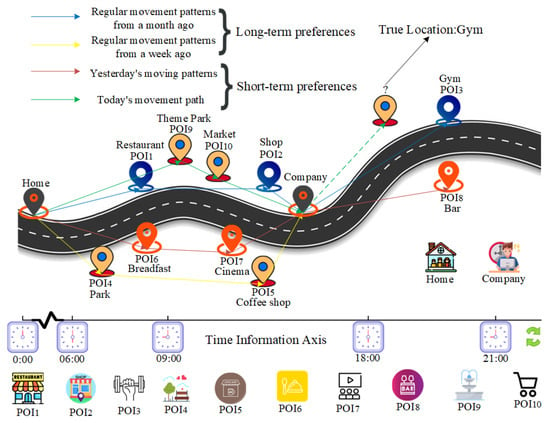
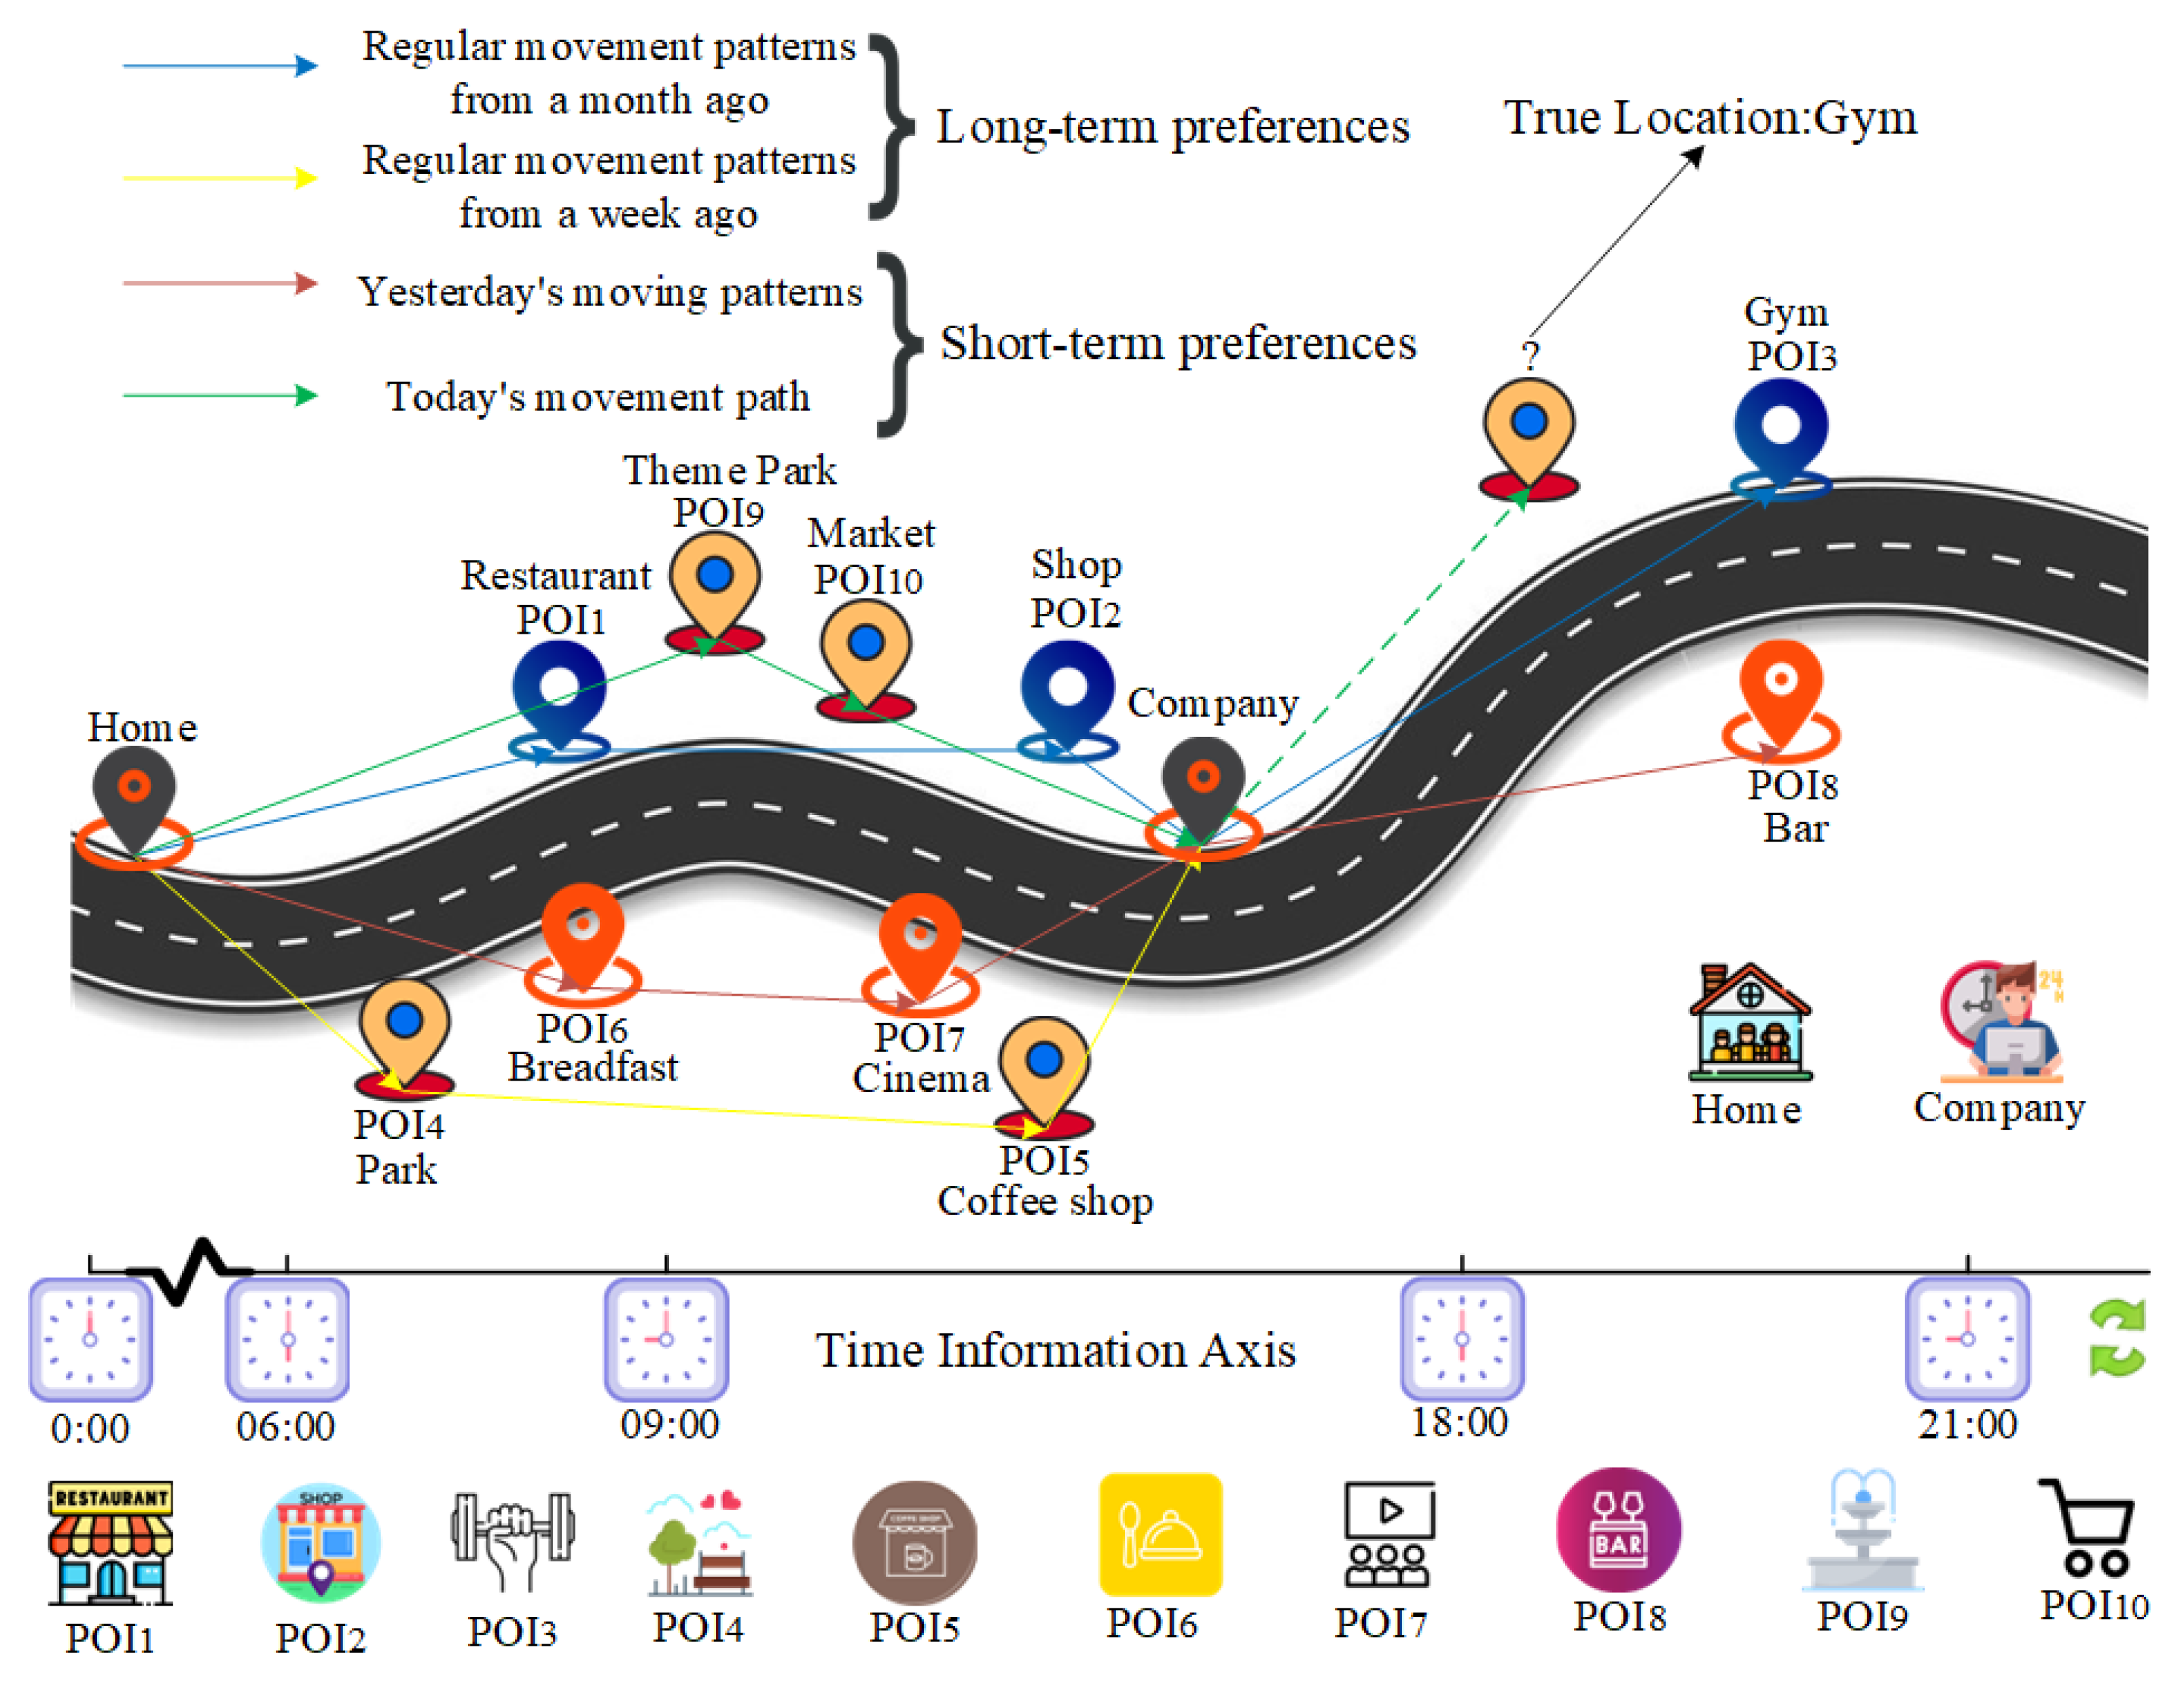
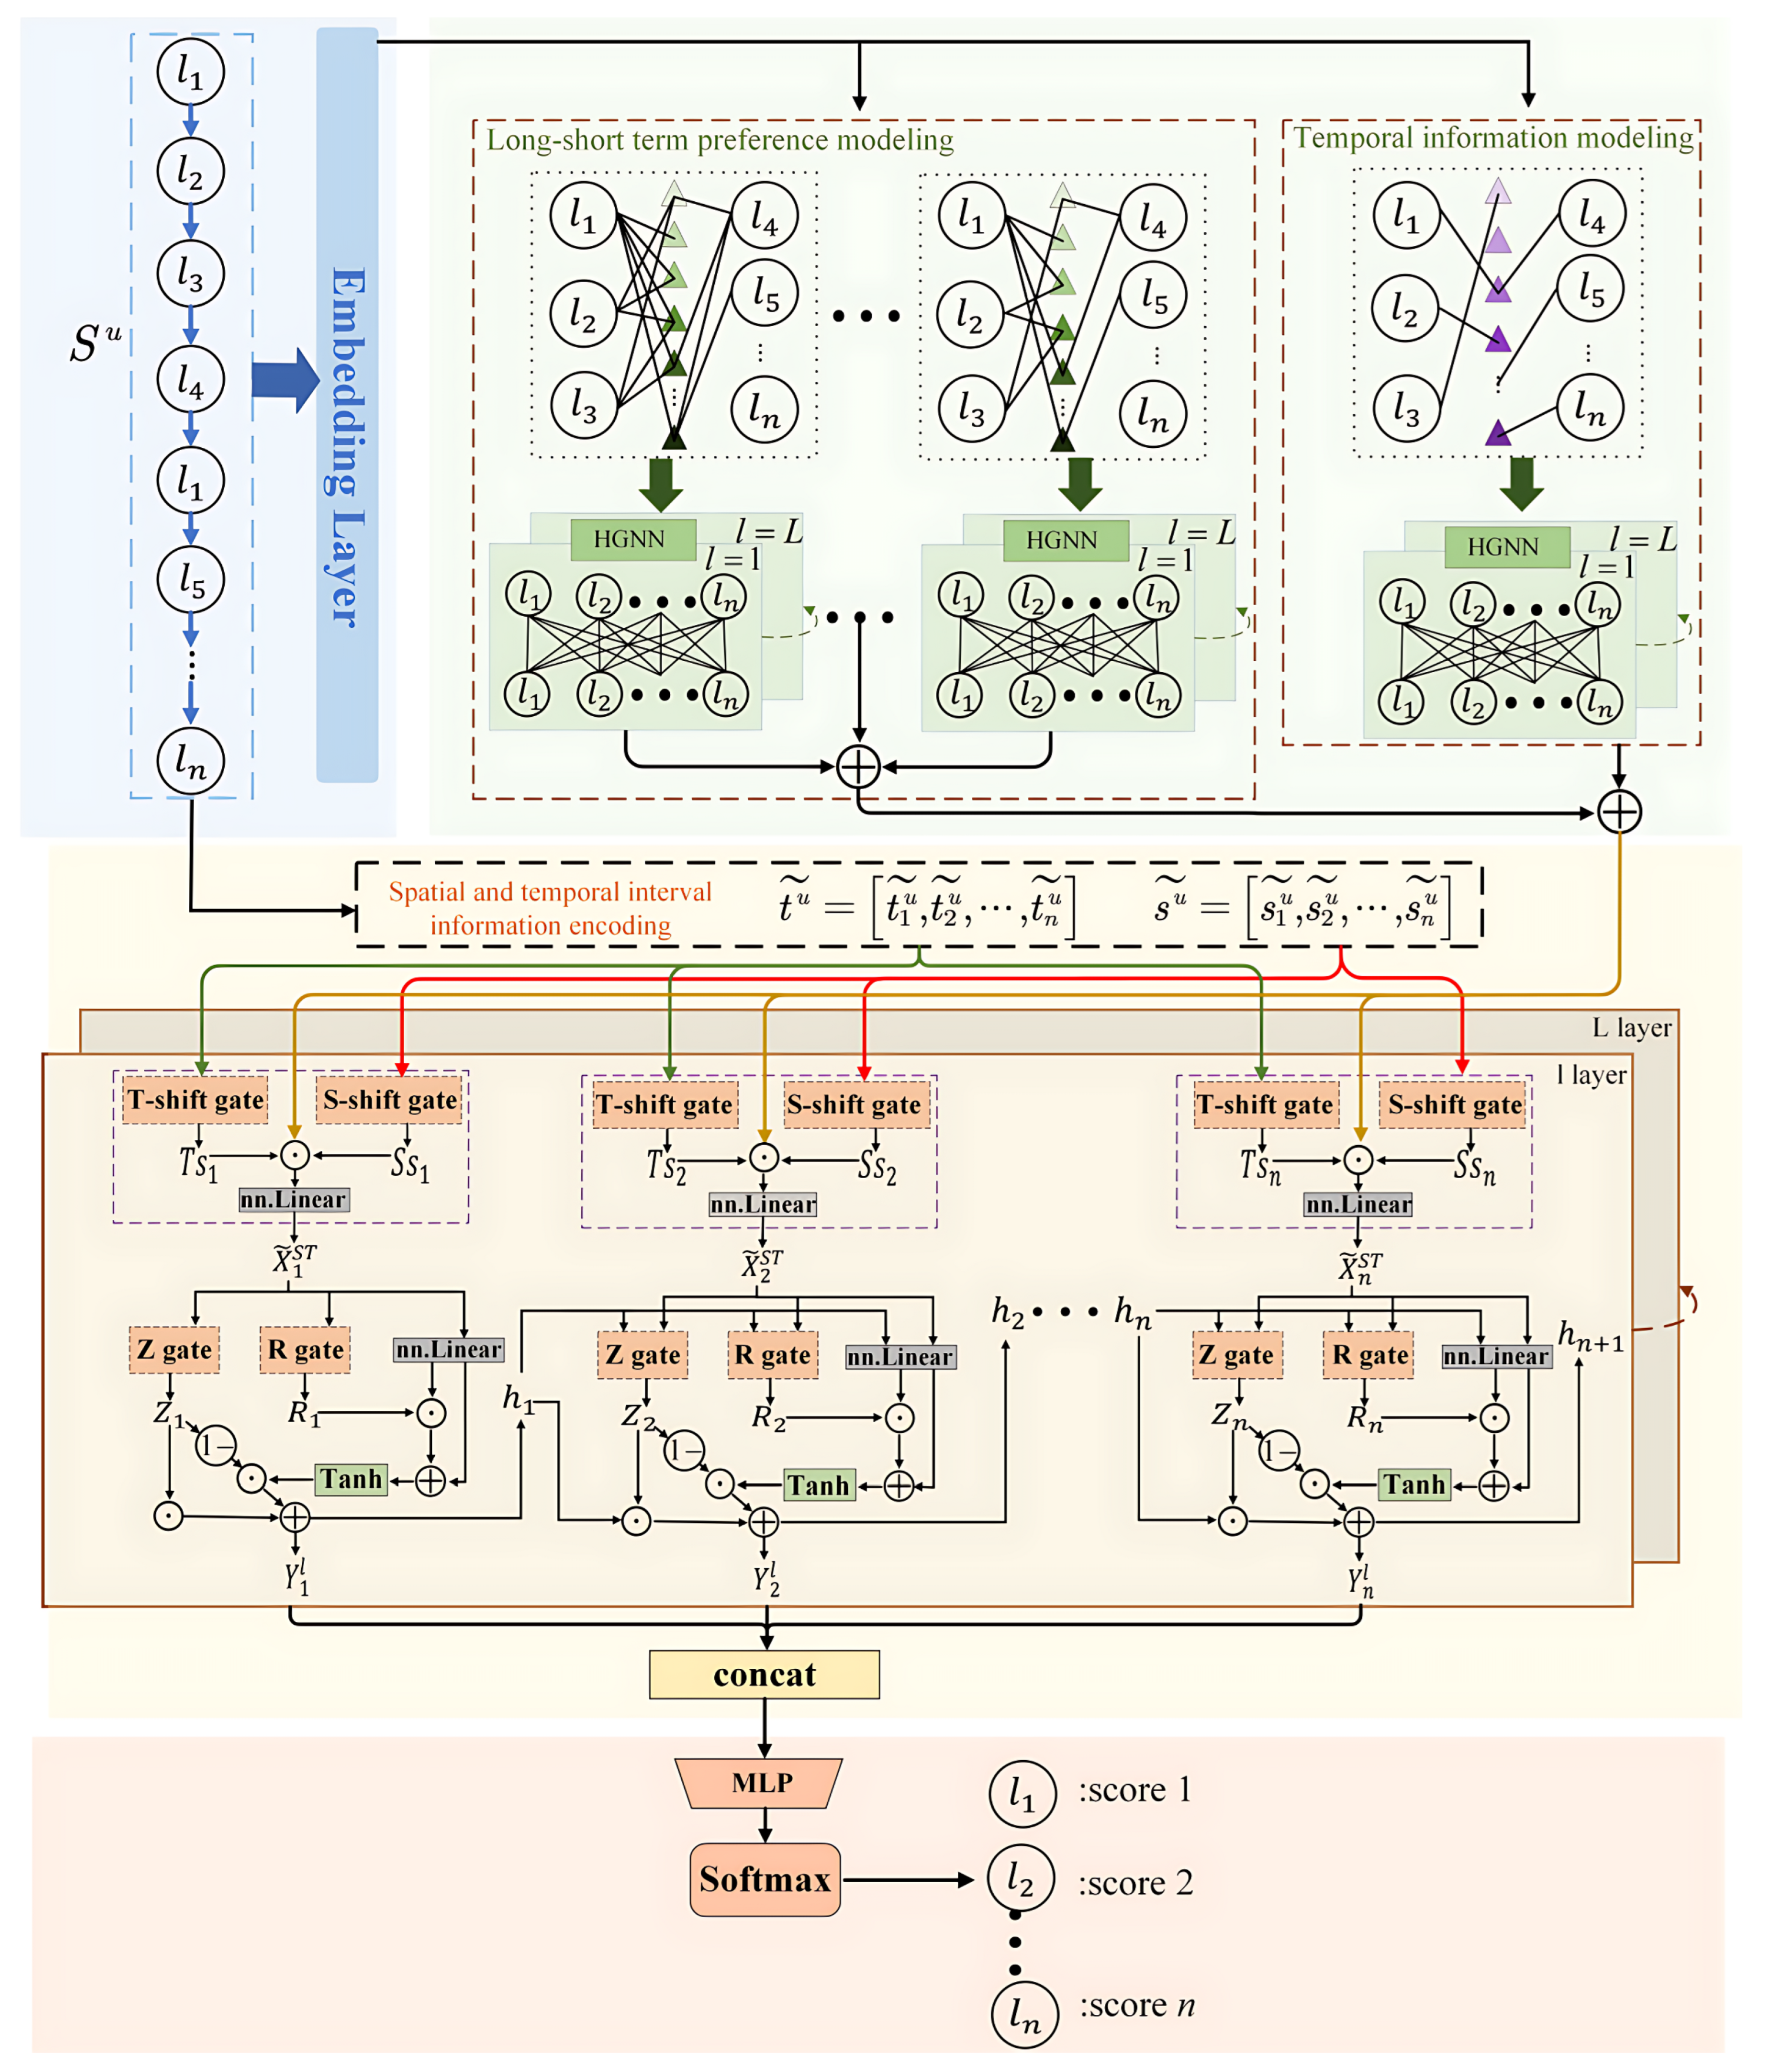
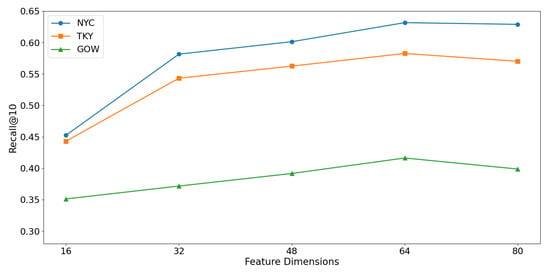
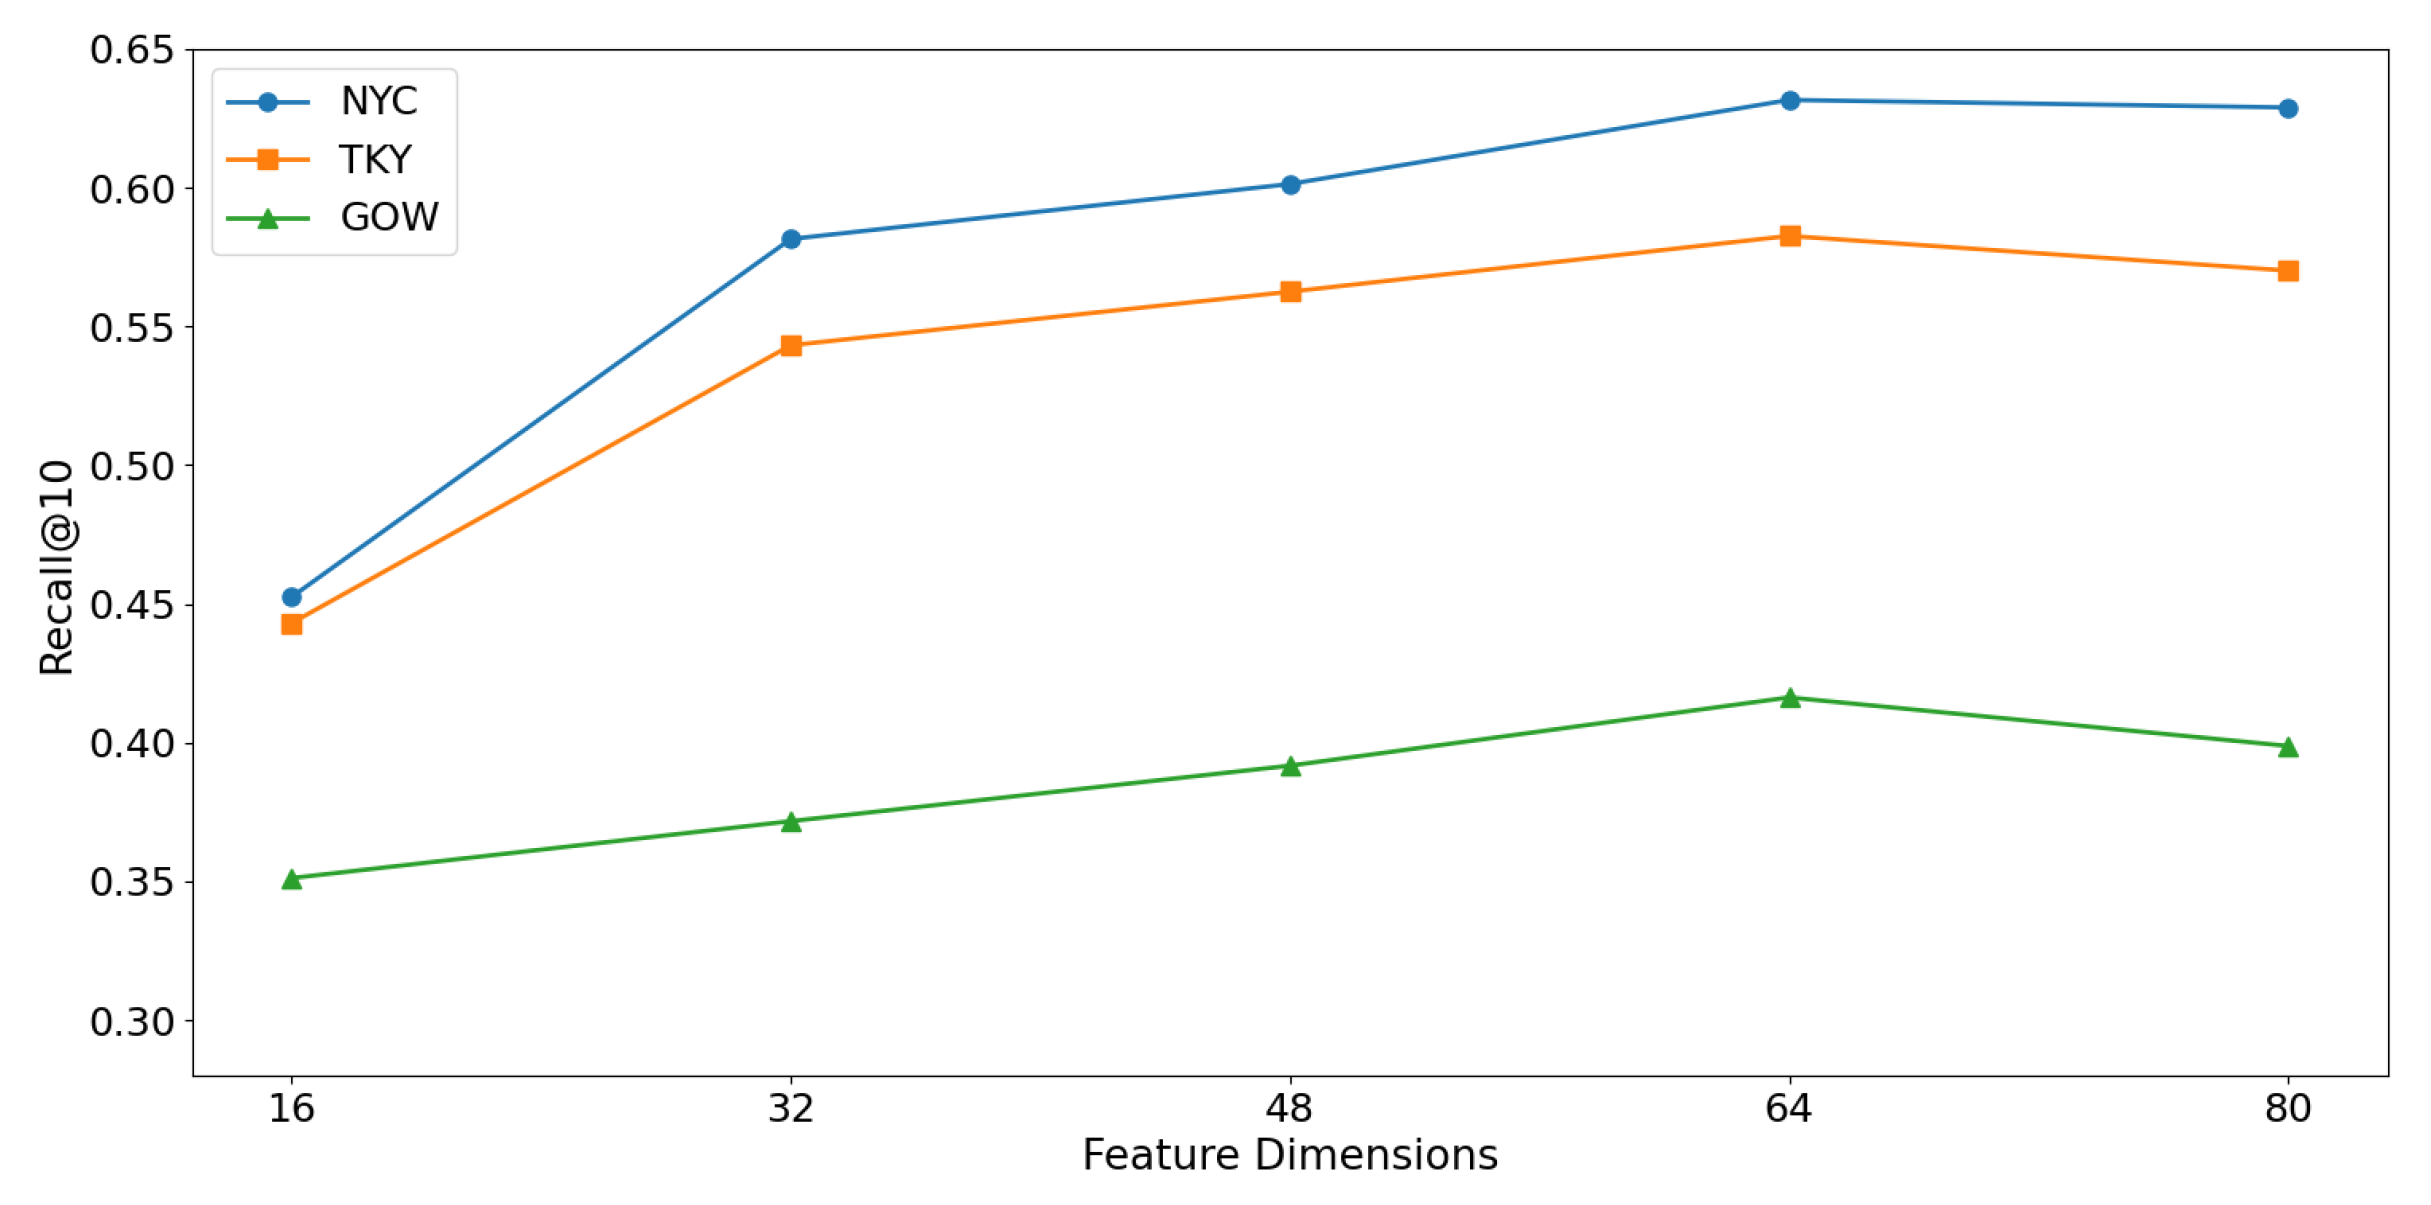
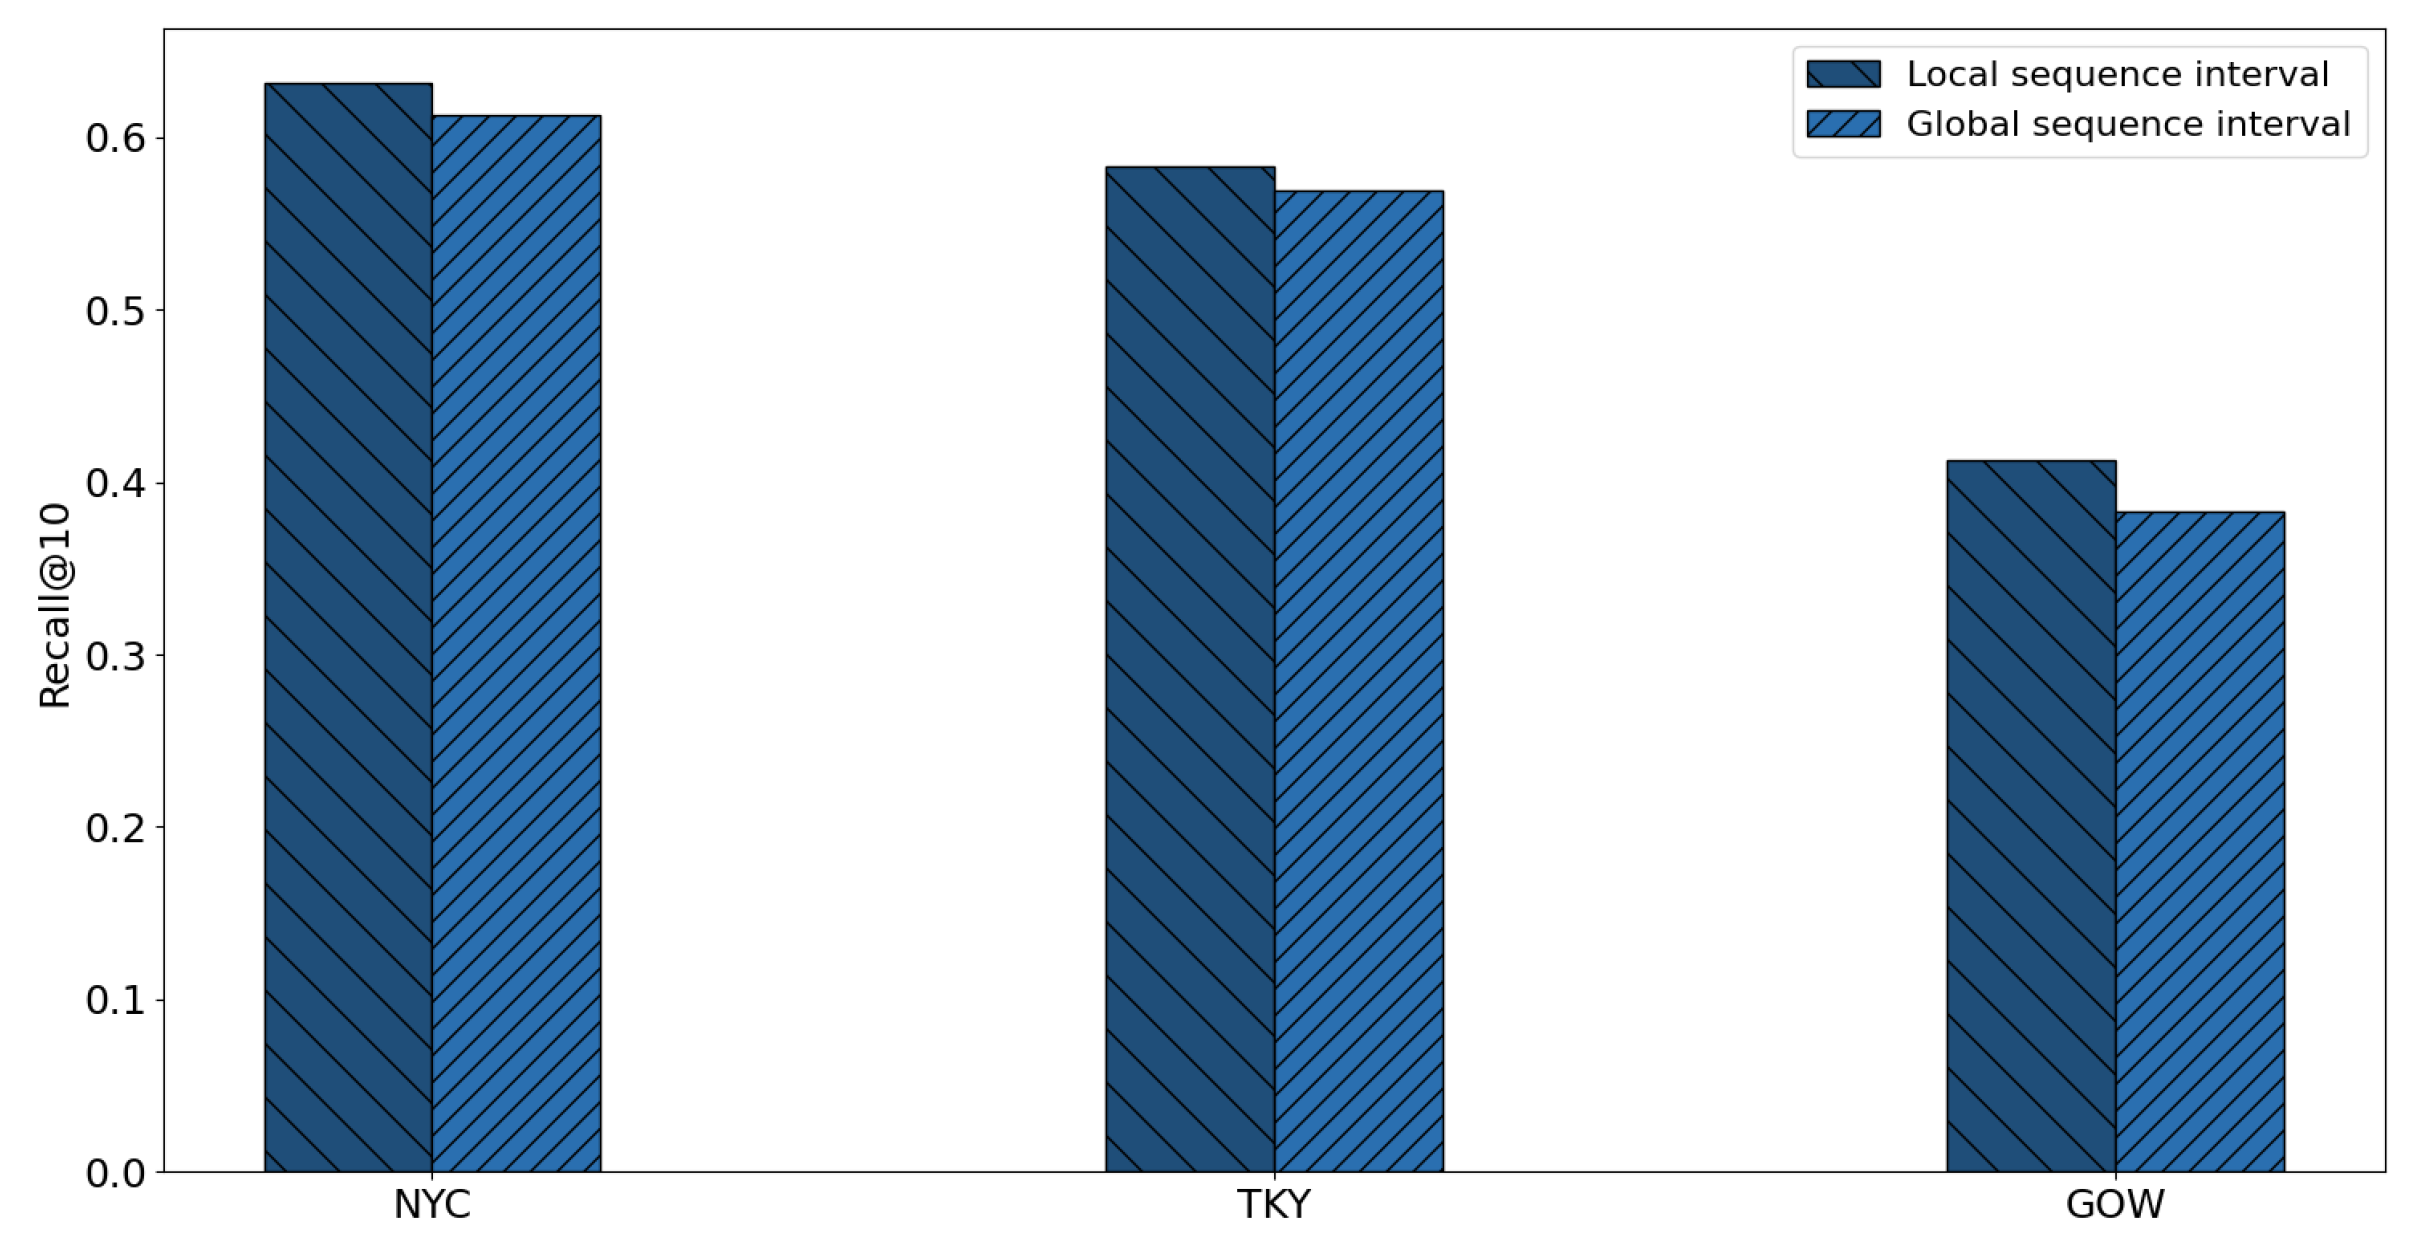
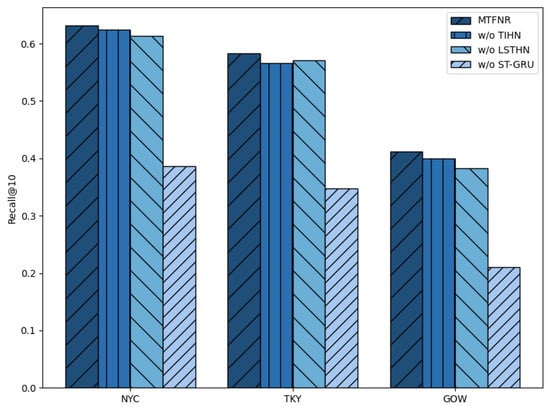
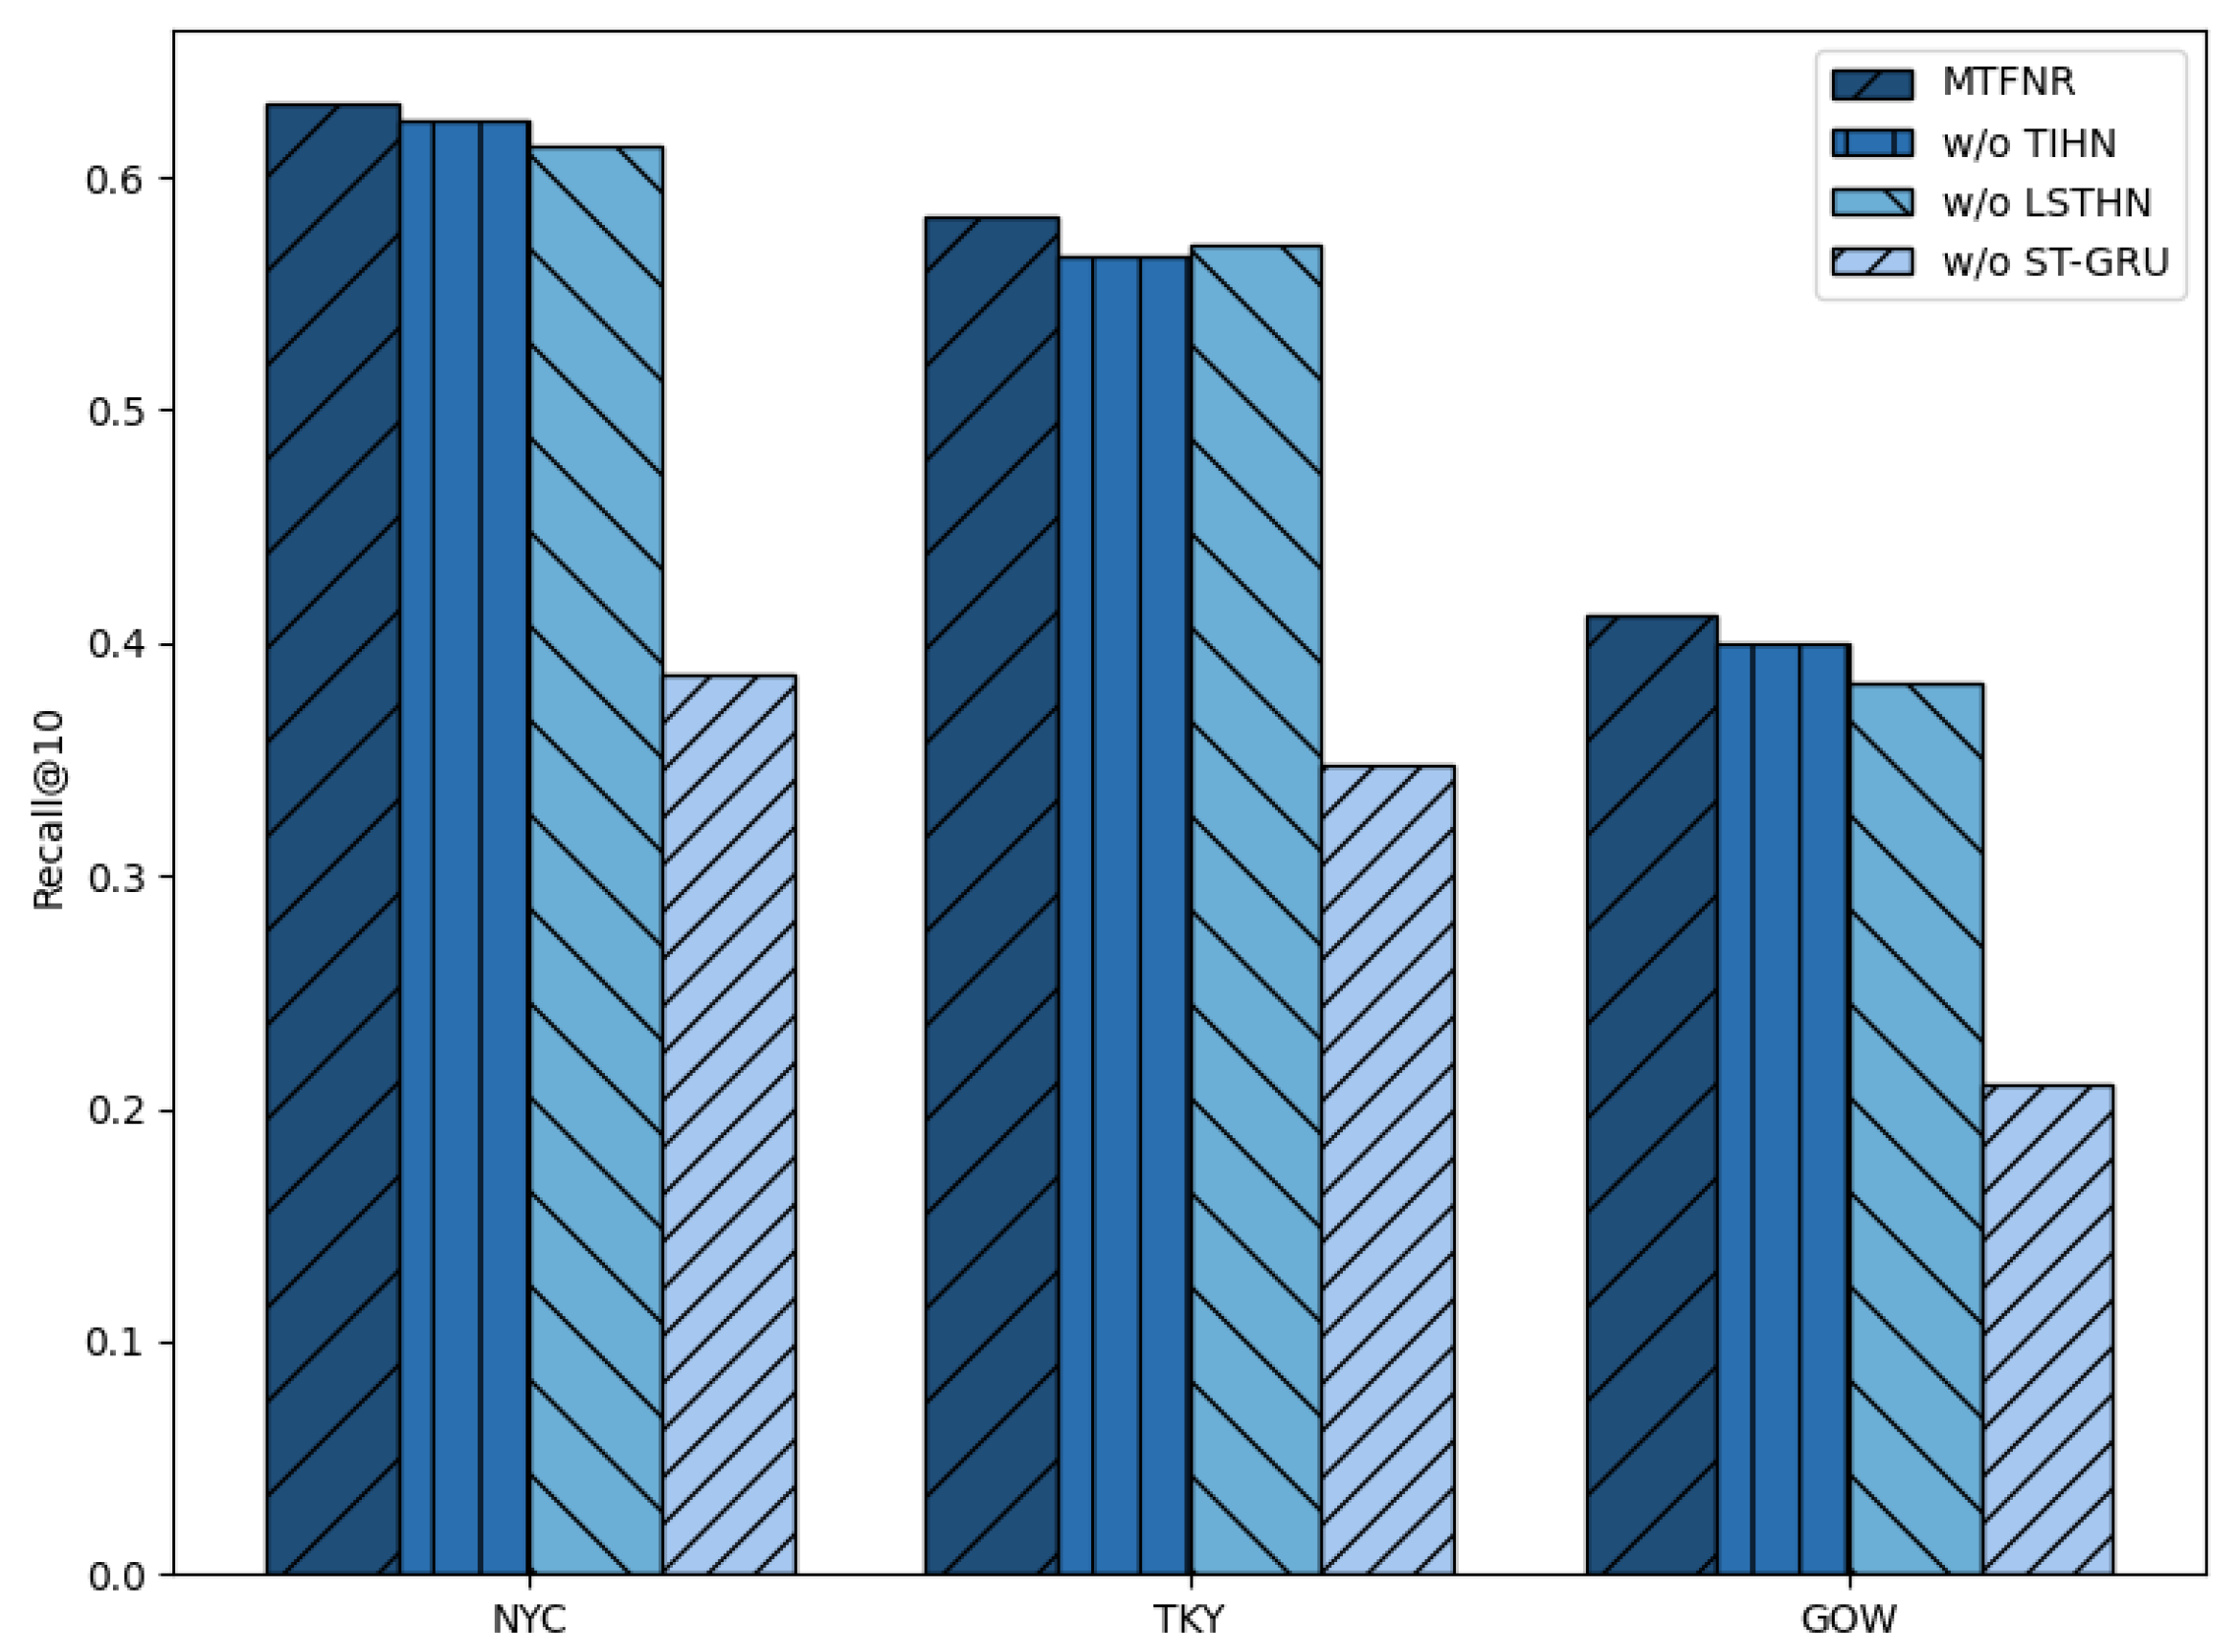
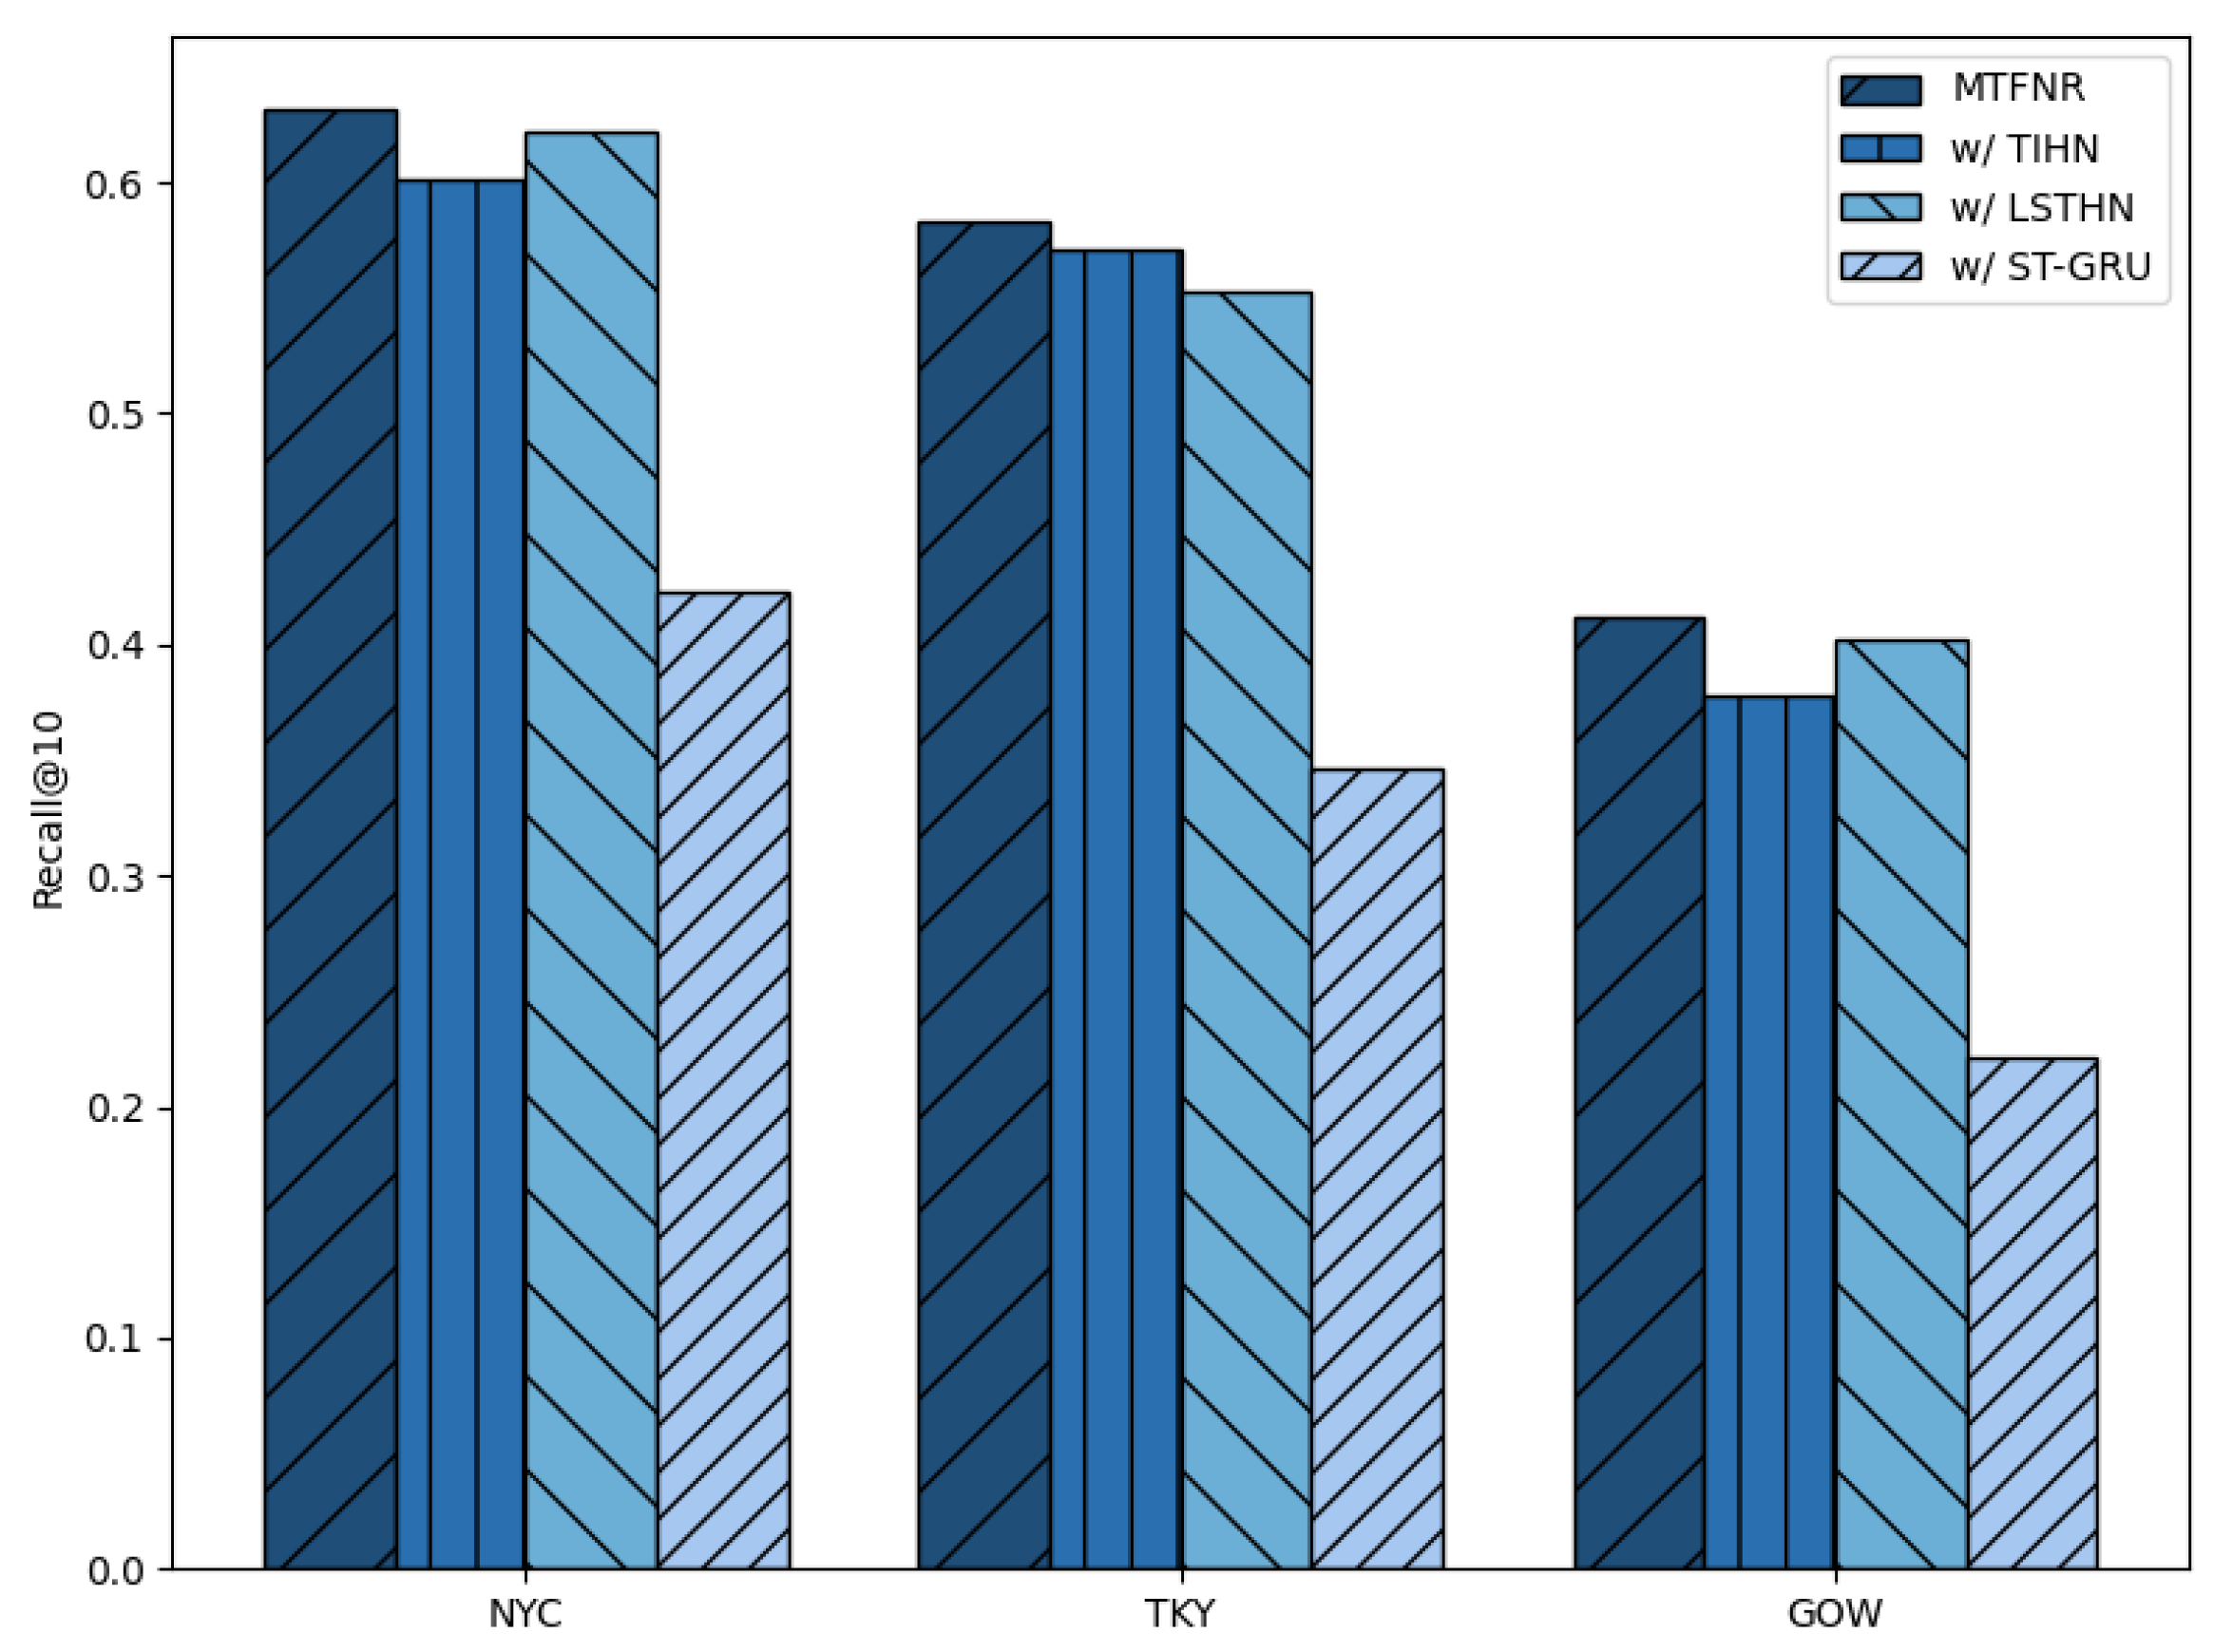
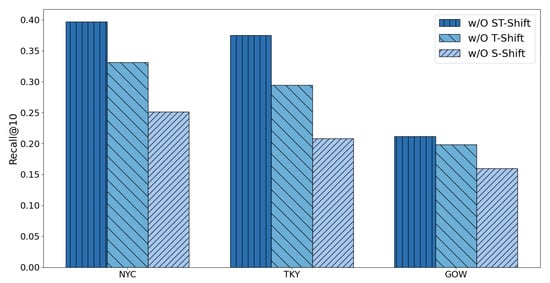
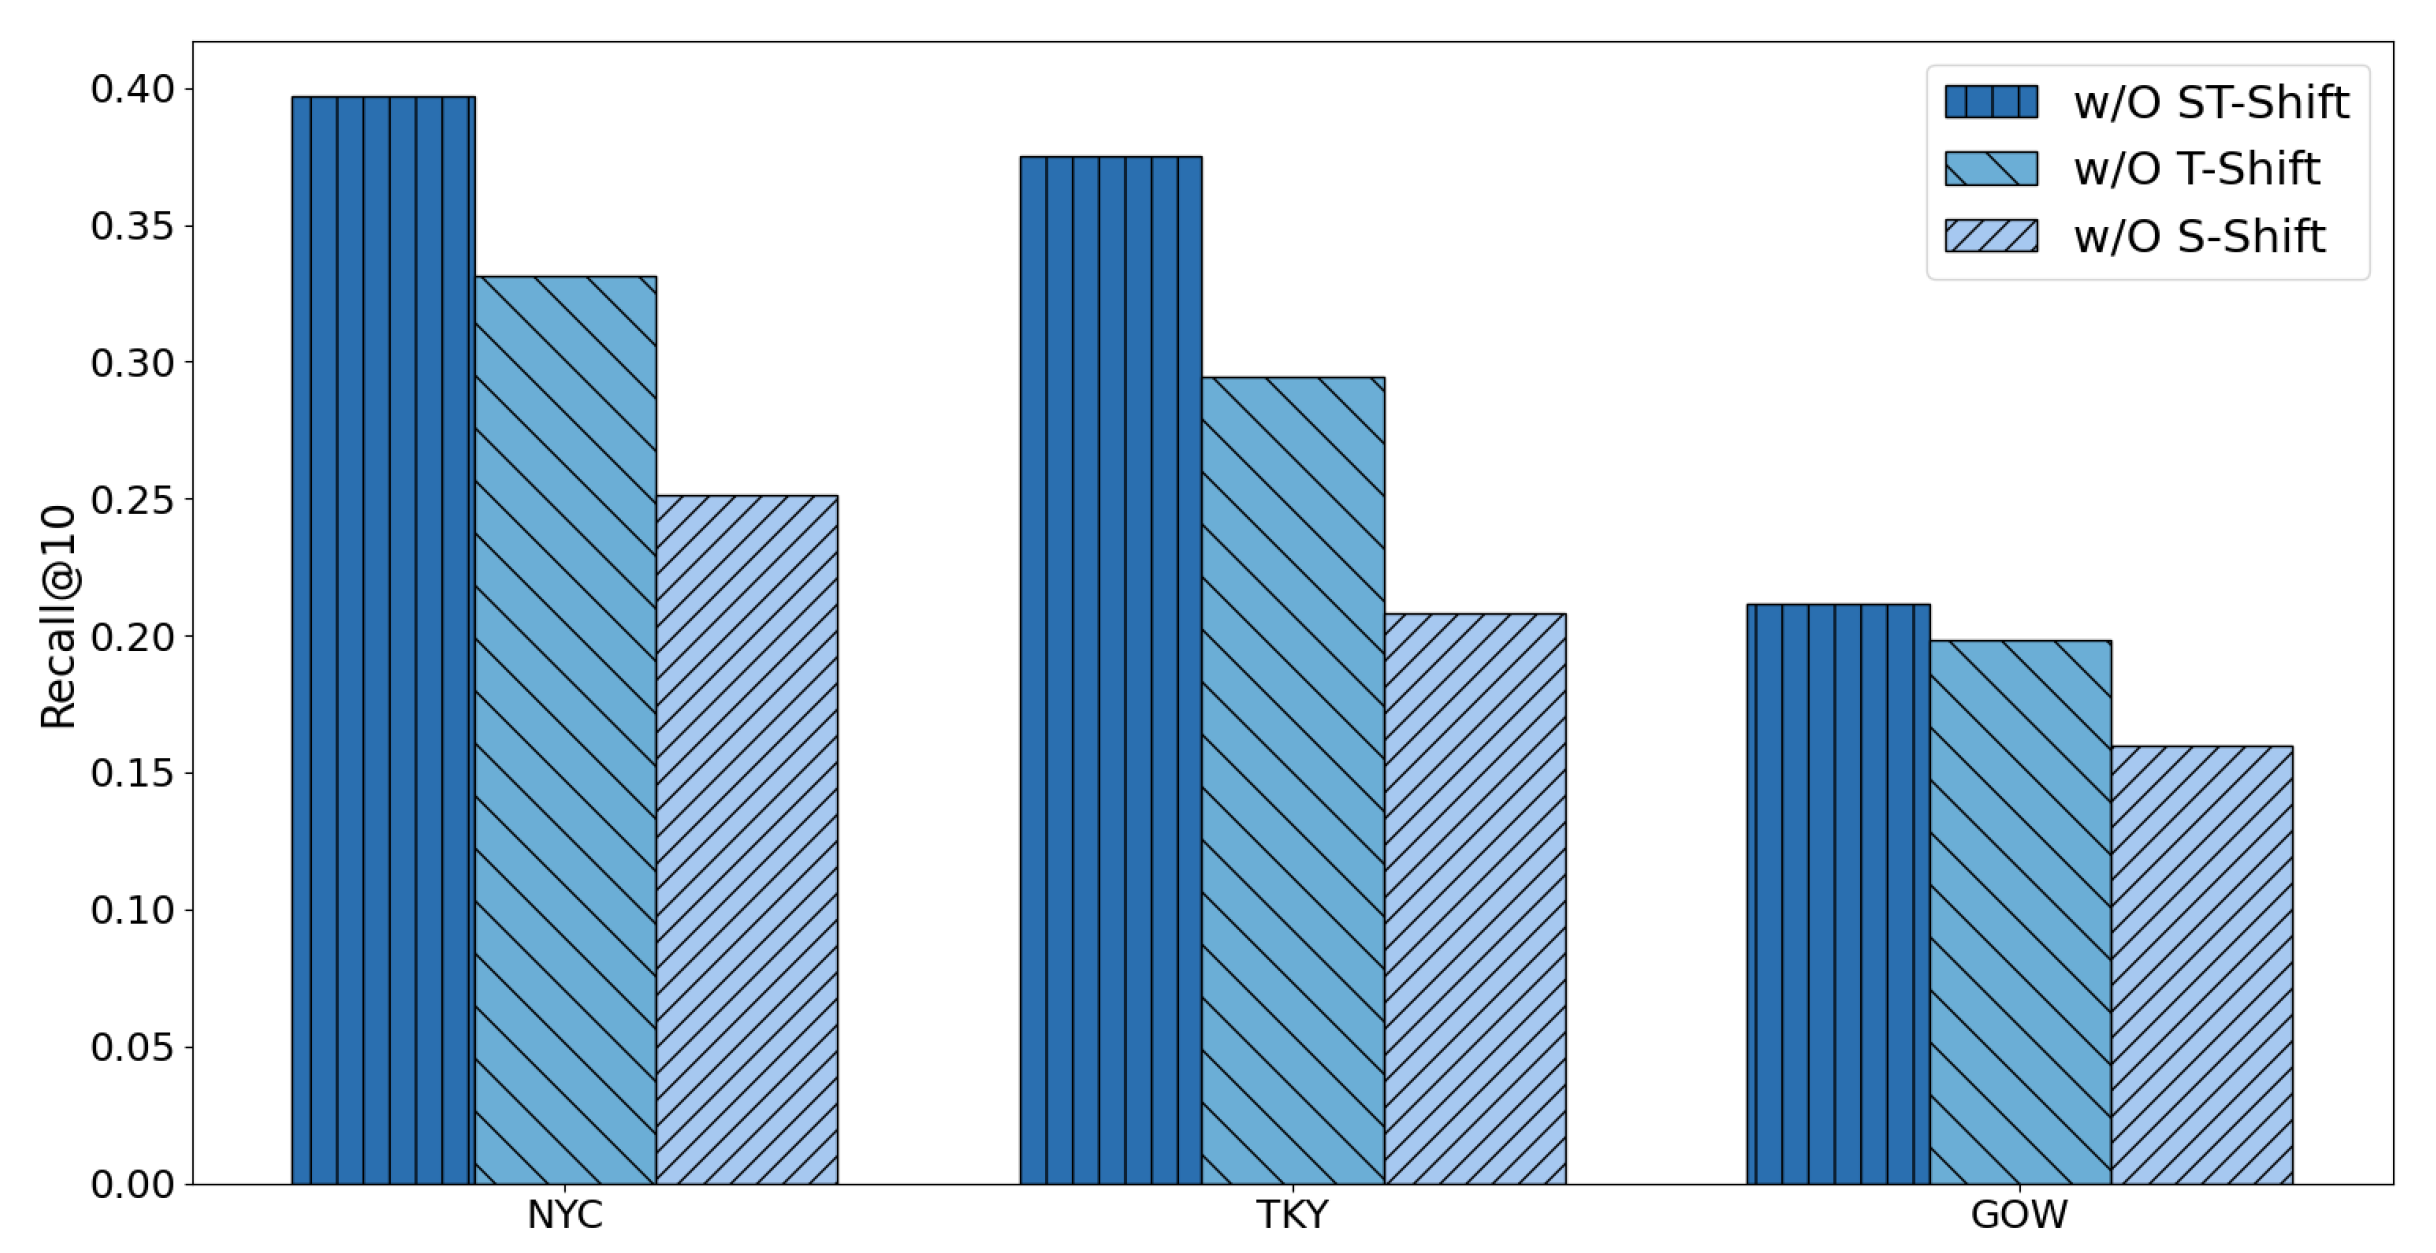
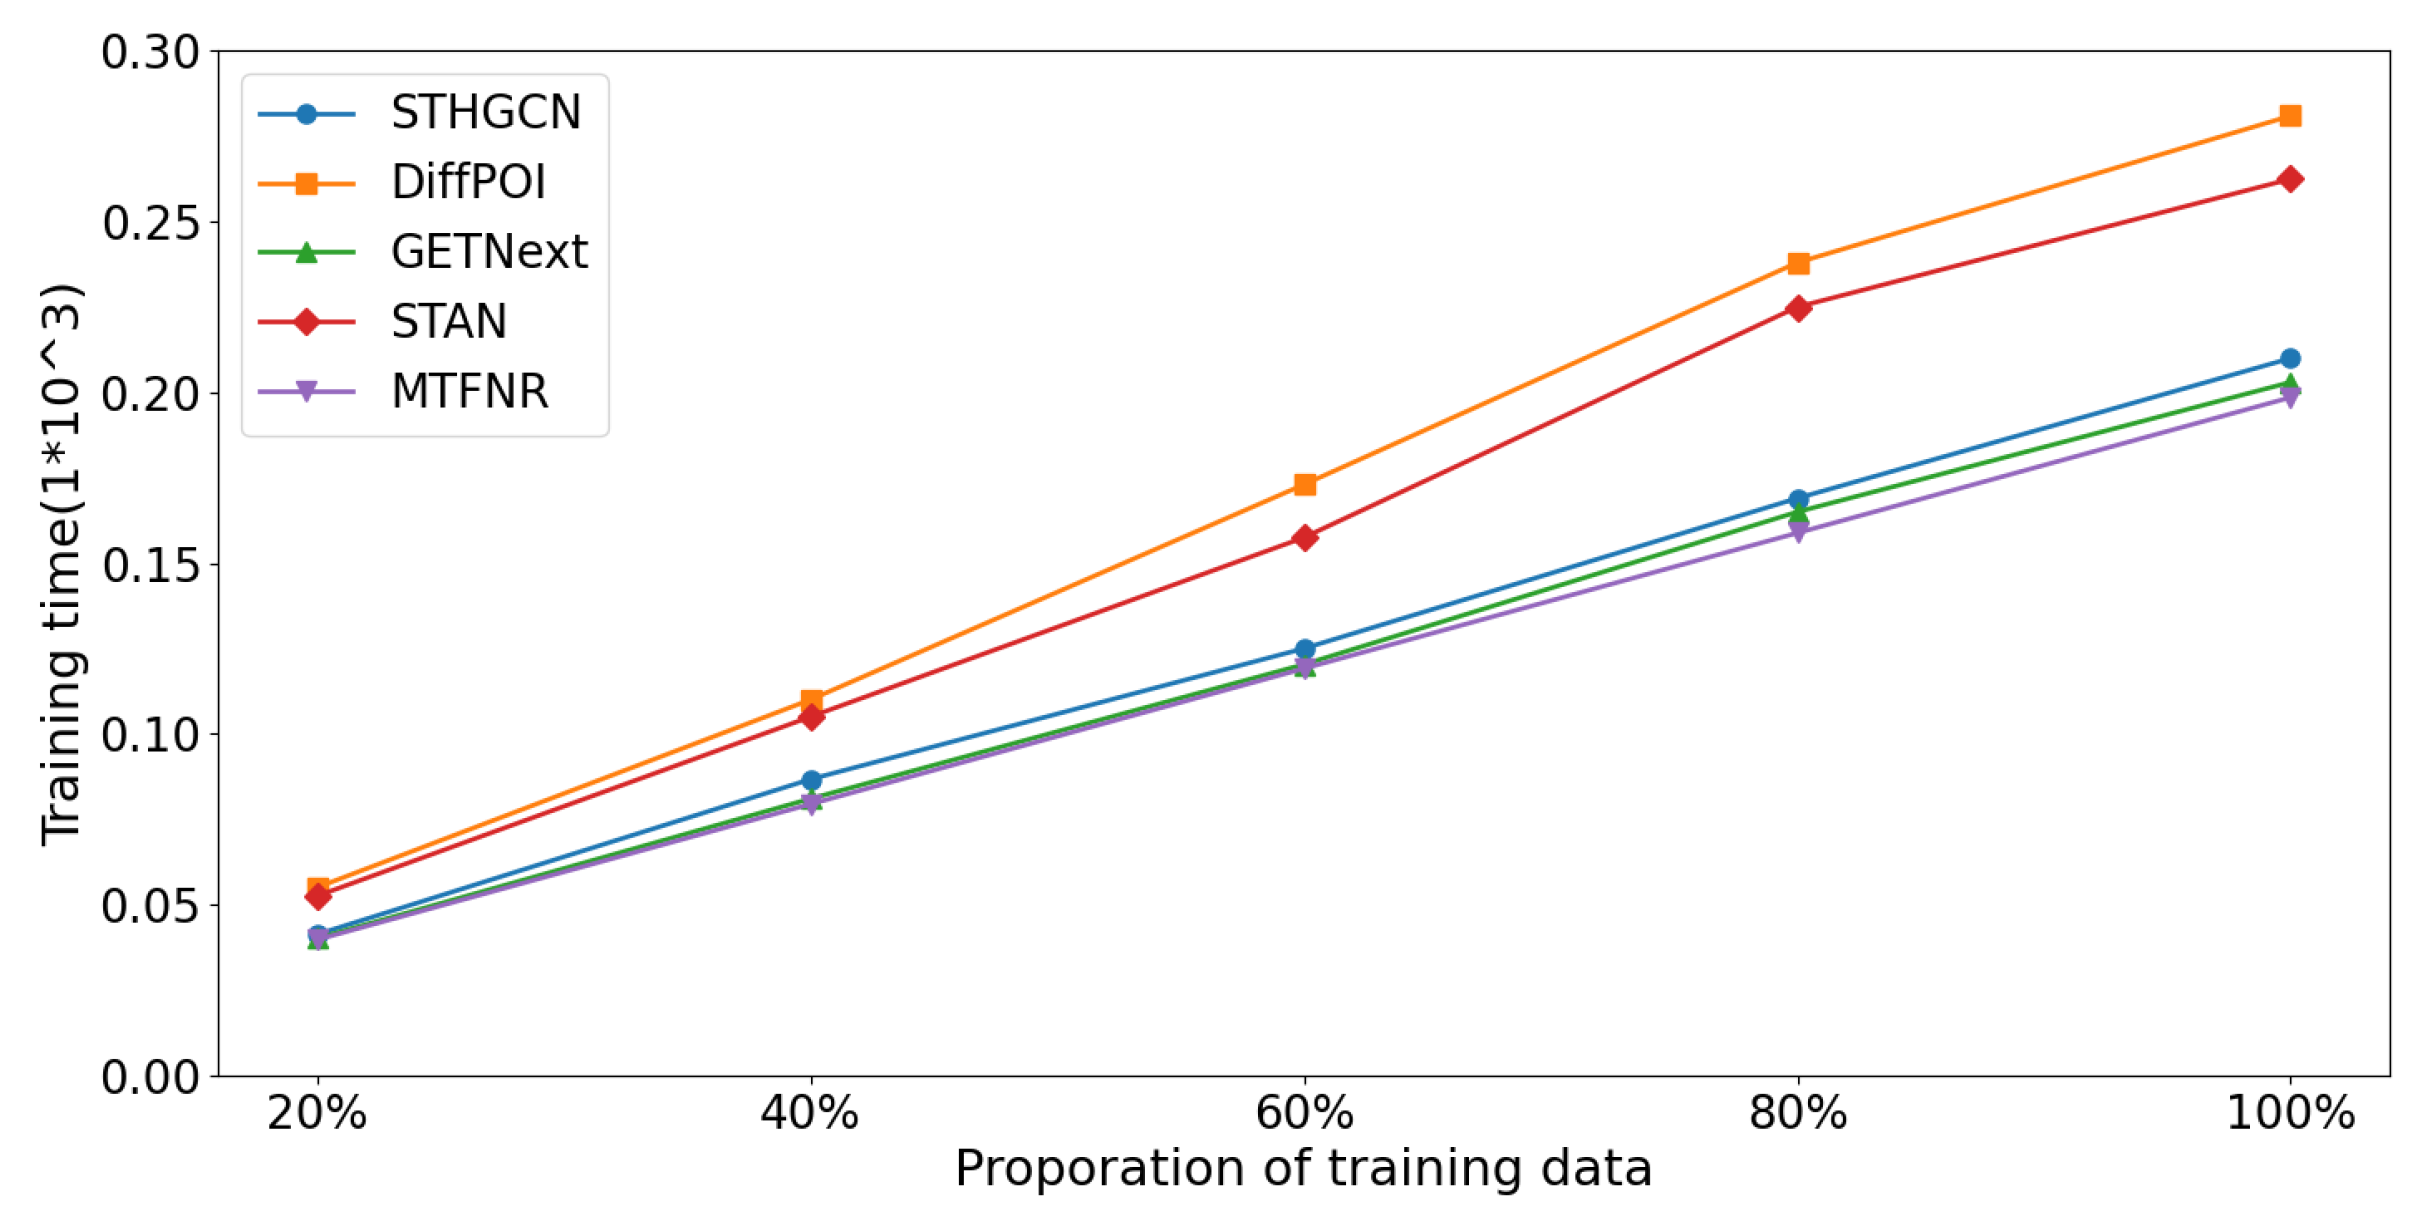

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.