Review

Grey Clustering Methods and Applications: A Bibliometric-Enhanced Review
1
Department of Accounting and Audit, Bucharest University of Economic Studies, 0105552 Bucharest, Romania
2
Department of Economic Informatics and Cybernetics, Bucharest University of Economic Studies, 0105552 Bucharest, Romania
3
Department of Economic Doctrines and Communications, Bucharest University of Economic Studies, 0105552 Bucharest, Romania
*
Author to whom correspondence should be addressed.
Mathematics 2025, 13(24), 4040; https://doi.org/10.3390/math13244040
Submission received: 14 November 2025 / Revised: 11 December 2025 / Accepted: 17 December 2025 / Published: 18 December 2025

Abstract

Grey systems theory has provided a change in paradigm related to how numbers and their mathematics are perceived. By including various levels of knowledge associated with the variables, the theory has succeeded in modelling systems characterised by incomplete or partially known information. Among the methods offered by the grey systems theory, the grey clustering approach offers a distinct perspective on clustering methodology by allowing researchers to define degrees of importance for the variables included in the analysis. Despite its expanding use across disciplines, a comprehensive synthesis of grey clustering research is lacking. In this context, this study aims to provide a comprehensive and structured overview of the research field associated with grey clustering and its applications, rather than the more rhetorical formulation previously included. By using a PRISMA approach, a dataset containing papers related to grey clustering is extracted from the Clarivate Web of Science database and analysed through bibliometric tools and further enhanced by providing thematic maps and topics discovery through the use of Latent Dirichlet Allocation (LDA) and BERTopic analyses. The final dataset includes 318 articles, and their examination allows for a detailed assessment of publication trends, thematic structures, and methodological directions. The annual scientific production showcased an increase of 10.78%, while the thematic analysis revealed key themes related to performance management, risk assessment, evaluation models for enhancing organisational performance, urban and regional planning, civil engineering, industrial engineering and automation, and risk evaluation for health-related issues. Additionally, a detailed review of the most-cited papers has been performed to highlight the role of grey clustering in various research fields.
MSC:
62-07; 90B50; 91B06; 93A30

1. Introduction

Grey systems theory represents an important subject within the academic community, and it was introduced for the first time in the manuscript written by Deng [1] in March 1982. The author explained in his work the “black box” concept and the difference between “black system” (completely unknown information), “grey system” (partially known information—incomplete), and “white system” (completely known information). Another concept that was introduced by Deng [1] refers to “grey matrix”, which is composed of both known and unknown properties, and through mathematical demonstrations, the controllability and stability aspects are discussed and clarified.
Despite the substantial growth of research grounded in grey systems theory, no existing bibliometric study has focused exclusively on grey clustering as a methodological subfield. Prior reviews have either examined the entire grey systems theory landscape or investigated GST applications within specific thematic contexts. For instance, Hu and Liu [2] restricted their analysis to sustainability-related studies, for a limited period of time, namely 2011–2021. Pan et al. [3] and Yang et al. [4] provided broad reviews of GST without distinguishing between its methodological branches, while Delcea [5] concentrated on grey-systems-based studies in economics. Other bibliometric studies targeted narrow application areas—engineering [6], supply chain management [7], decision-making under uncertainty [8], supplier selection [9], or sustainable digitalisation [10]—but none isolated grey clustering as an independent object of analysis.
However, grey clustering represents a distinct methodological part of the grey systems theory, characterised by unique mathematical structures (e.g., possibilistic whitenisation weight functions, offering various importance to particular variables when conducting the analysis), featuring a wide range of diverse variants (classical grey clustering, weighted and entropy-based clustering, fuzzy–grey hybrids, and cloud-integrated models), and rapidly expanding applications across a series of practical research areas, such as, but not limited to environmental evaluation, engineering diagnostics, healthcare, industrial risk assessment, and urban planning. The distinctive capacity of grey clustering methods to accommodate incomplete, imprecise, or interval-based information sets this type of method apart from other submethods that can be encountered within the grey systems theory, such as grey prediction or grey relational analysis. Consequently, understanding grey clustering’s scholarly evolution, methodological diversification, and thematic trajectories requires an analysis that is not subsumed within broader grey systems bibliometric studies.
Although it is noticed in a wide variety of bibliometric reviews, across various subjects, in the scientific literature, there is no paper that focuses exclusively on grey clustering, more specifically on its methods and applications in real life. Most of the papers address general domains, such as grey systems, and do not take into consideration particular aspects related to this subfield. Apart from these, the papers that are already published do not include the latest research contributions, advanced analytical tools’ integration, comprehensive reviews, and thematic evolutions.
The present paper fills this gap by offering the first bibliometric-enhanced systematic review dedicated solely to grey clustering. Unlike previous GST reviews, our study:
  • Uses a comprehensive and up-to-date dataset capturing all WoS-indexed articles explicitly employing grey clustering;
  • Integrates classical bibliometric indicators with thematic evolution mapping;
  • Employs advanced topic modelling techniques (LDA and BERTopic) to uncover methodological directions, domain applications, and emerging research frontiers.
By consolidating fragmented contributions across disciplines, the paper provides the first structured and empirically grounded synthesis of grey clustering research, highlighting its conceptual development, areas of application, and unresolved challenges.
Therefore, it should be highlighted once more that the focus of the present paper is on grey clustering, and not on general aspects related to grey systems theory, and involves a large and up-to-date set of papers, examined through multiple perspectives. It combines elements from bibliometric studies with components from review research, together with some advanced topic modelling approaches (LDA and BERTopic). Thus, substantial attention is dedicated to thematic evolution, offering a strong perspective of the field’s progress and uncovering, at the same time, the similarities and differences between addressed topics. In addition to the review of the top-10 most-cited articles about grey clustering, there is also a dedicated section in which the manuscripts are divided and summarised based on their themes. The fact that theoretical insights are combined with practical applications on the collected dataset (e.g., bibliometric indicators, LDA, BERTopic) offers readers a clear overview of the domain and uncovers crucial aspects related to the research field, such as trends, unexplored areas, gaps, and challenges.
The central questions that will be explored in the following pages are listed below:
  • RQ1: What is the yearly distribution of the studies associated with grey clustering?
  • RQ2: What are the topics addressed in the top-10 most-cited documents?
  • RQ3: How do the research themes in grey clustering evolve over time?
  • RQ4: What are the core topics revealed through Latent Dirichlet Allocation (LDA) and BERTopic?
  • RQ5: What are the main findings, challenges, and research gaps identified in the scientific literature when grey clustering is considered?
  • The questions’ selection was carefully performed, considering the scope of the research and the methods involved. The PRISMA flowchart represents the foundation of all questions, as it assists authors in selecting the relevant set of data used in the investigation. The answers for the first three questions are uncovered by the bibliometric investigation (e.g., scientific production evolution, top-10 most-cited documents, co-occurrence networks, thematic maps). For the fourth question, the findings offered by the thematic maps’ evolution are further complemented by the involvement of advanced topic-modelling methods (LDA and BERTopic), which provide a deeper thematic examination. The last question refers to the final synthesis of the results, being more oriented towards a qualitative content analysis.
  • The article is divided into five sections. The first section (Section 1) offers an overview of the study, along with the scope of research, while the second one (Section 2) discusses some of the works in the field of grey clustering, as well as points out the main types of grey clustering. Next, Section 3 presents the main tools used in the investigation. The fourth section (Section 4) includes the actual investigation, presents the main details about the collected set of data, summarises the top-10 most-cited papers, discusses the thematic evolution, identifies the research topics through LDA and BERTopic, and then includes a dedicated section for papers’ reviews based on subjects. The next section (Section 5) uncovers the main constraints of the study, while the last section (Section 6) outlines the final remarks and their significance.

2. Brief Introduction to Research in Grey Clustering

The scientists’ considerable interest in grey systems theory is further proved by the increased number of papers published in the academic community that address the use of this methodology in various domains. For instance, the paper written by Mukherjee and Kar [11] is oriented towards combining grey systems with fuzzy mathematics, in the education sector, for evaluating the students’ answers. Pam et al. [12] conducted research about the grey systems theory application in construction projects, which aims to select the optimal paint suppliers and prioritise assessment factors in uncertain contexts. Peng et al. [13] were discussing the circular economy, with a particular focus on the e-commerce market. They utilised grey systems theory for predicting market trends, uncovering critical issues, and addressing current challenges. Majchrzak and Więcek-Janka [14] explored the relationship between family firms’ internal and external communication and their market behaviour. By involving a sample of 20 enterprises and by applying grey systems theory, it was uncovered that external communication determines a progressive market position, while internal communication leads to a traditional one.
Grey clustering is a popular method used by academics for classifying data into distinct groups, known as “clusters” [15]. It is based on grey systems theory and guides decision-making processes in uncertain conditions, involving known or partially known information. In terms of applications presented in the scientific literature in connection with grey clustering, the following works can be mentioned. Liu et al. [16] proposed an evaluation system based on grey clustering and entropy weight, which helps in evaluating the English teaching quality in college. Also, the article written by Delgado et al. [17] investigates the industrial hygiene in the beer industry, involving a case study from Peru. The authors used a grey clustering method for identifying, analysing, and assessing the risk factors in the field, and demonstrated that the level of hygiene is acceptable. Furthermore, Karimi and Ahmadian [18] published a manuscript focused on the bank branch performance, using the grey clustering method combined with a grey two-stage data envelopment analysis model. This approach outperformed the traditional techniques and demonstrated efficiency in building the ranking, planning, and decision-making. Additionally, Liang et al. [19] analysed 117 new-energy companies from China, focusing on their growth and classification, using a grey clustering model. The insights uncovered in the paper are important for the industry’s sustainable development and implementation of new strategies.
Based on the scientific literature [20,21,22,23,24,25], various types of grey clustering analysis can be encountered, each of them coming with advantages and disadvantages, as well as particularities in being applied in various research areas—please consider the information in Table 1.
Considering all this information, the present paper aims to further contribute to the scientific literature and provide a comprehensive overview of the existing research related to grey clustering methods and applications.

3. Materials and Methods

The purpose of this section is to discuss the main materials and methods involved in the present manuscript.
For extracting the set of data, it was chosen a single-database approach was chosen, a decision supported by several arguments, which are all elaborated below.
The Web of Science Core Collection (WoS) database [26] is found among the authors’ top preferences for gathering the sets of data, especially in bibliometric research [27], as it includes a large variety of papers written across numerous topics by scientists from all over the world, it has an up-to-date version, accessible interface design, and enjoys a high popularity and substantial recognition within the academic community. All these benefits are further discussed by Cobo et al. [28] and Bakir et al. [29] in their papers.
Liu [30] and Liu [31] highlight in their articles the importance of having full access to sources in the WoS database for obtaining an accurate set of data. In the case of this paper, access to all 10 indices was available:
  • Science Citation Index Expanded (SCIE)—1900–present.
  • Social Sciences Citation Index (SSCI)—1975–present.
  • Arts & Humanities Citation Index (A&HCI)—1975–present.
  • Emerging Sources Citation Index (ESCI)—2005–present.
  • Conference Proceedings Citation Index—Science (CPCI-S)—1990–present.
  • Conference Proceedings Citation Index—Social Sciences and Humanities (CPCI-SSH)—1990–present.
  • Book Citation Index—Science (BKCI-S)—2010–present.
  • Book Citation Index—Social Sciences and Humanities (BKCI-SSH)—2010–present.
  • Current Chemical Reactions (CCR-Expanded)—2010–present.
  • Index Chemicus (IC)—2010–present.
The WoS database’s ease of integration with the scientometric tools (Biblioshiny, VOSviewer, and CiteSpace), utilised for generating the figures in the subsequent chapter, was another important aspect considered when this decision was made.
Apart from these, the presence of individualised analyses (e.g., the hierarchy of the most-cited articles) in the paper would have generated difficulties in shaping the tops in the case of a multiple database approach.
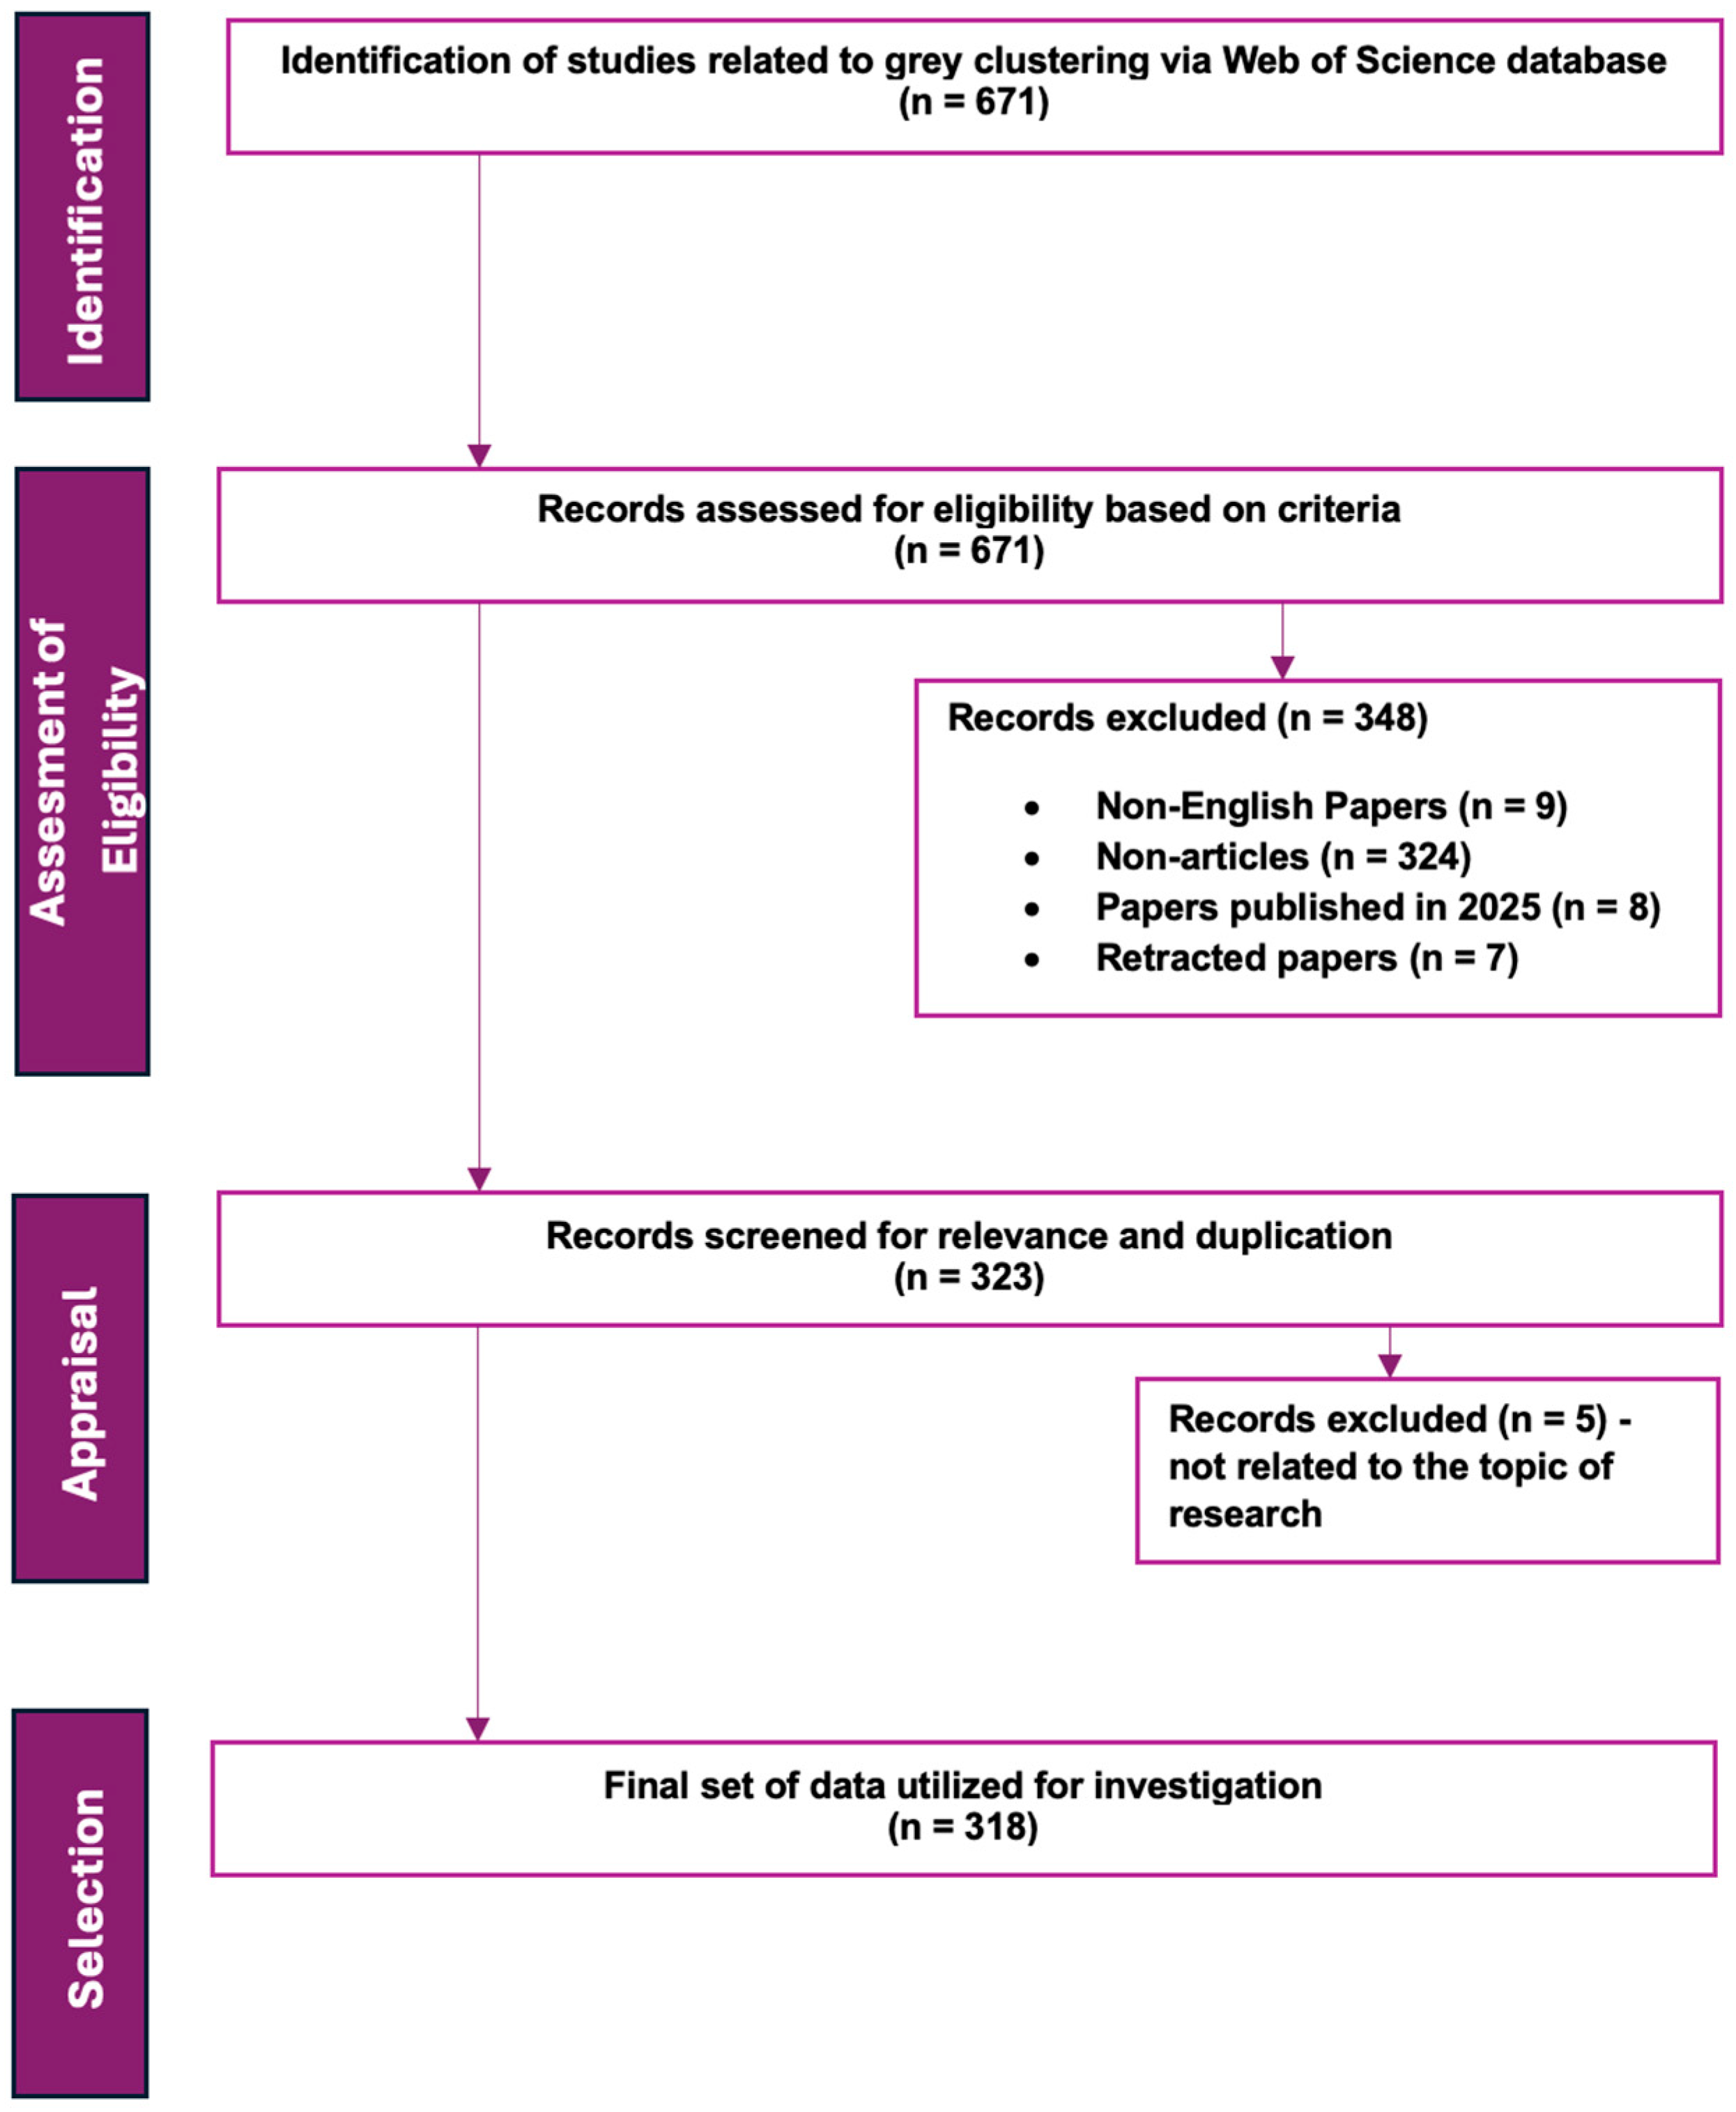
Figure 1 captures the PRISMA (Preferred Reporting Items for Systematic Reviews and Meta-Analyses) flowchart [32], which includes four distinct phases: identification (known as “Identification”), assessment of eligibility (known as “Screening”), appraisal (known as “Eligibility”), and selection (known as “Included”). The paper complies with the PRISMA guidelines, and a protocol registration has been made available at the following link: https://www.protocols.io/private/4E931982C09D11F0B8260A58A9FEAC02 (accessed on 13 November 2025), with a registered https://doi.org/10.17504/protocols.io.ewov11wdyvr2/v1. Additional information regarding the PRISMA checklist can be found in the Supplementary Materials.
The full description of the PRISMA steps provided in Figure 1 can be read in Appendix A.
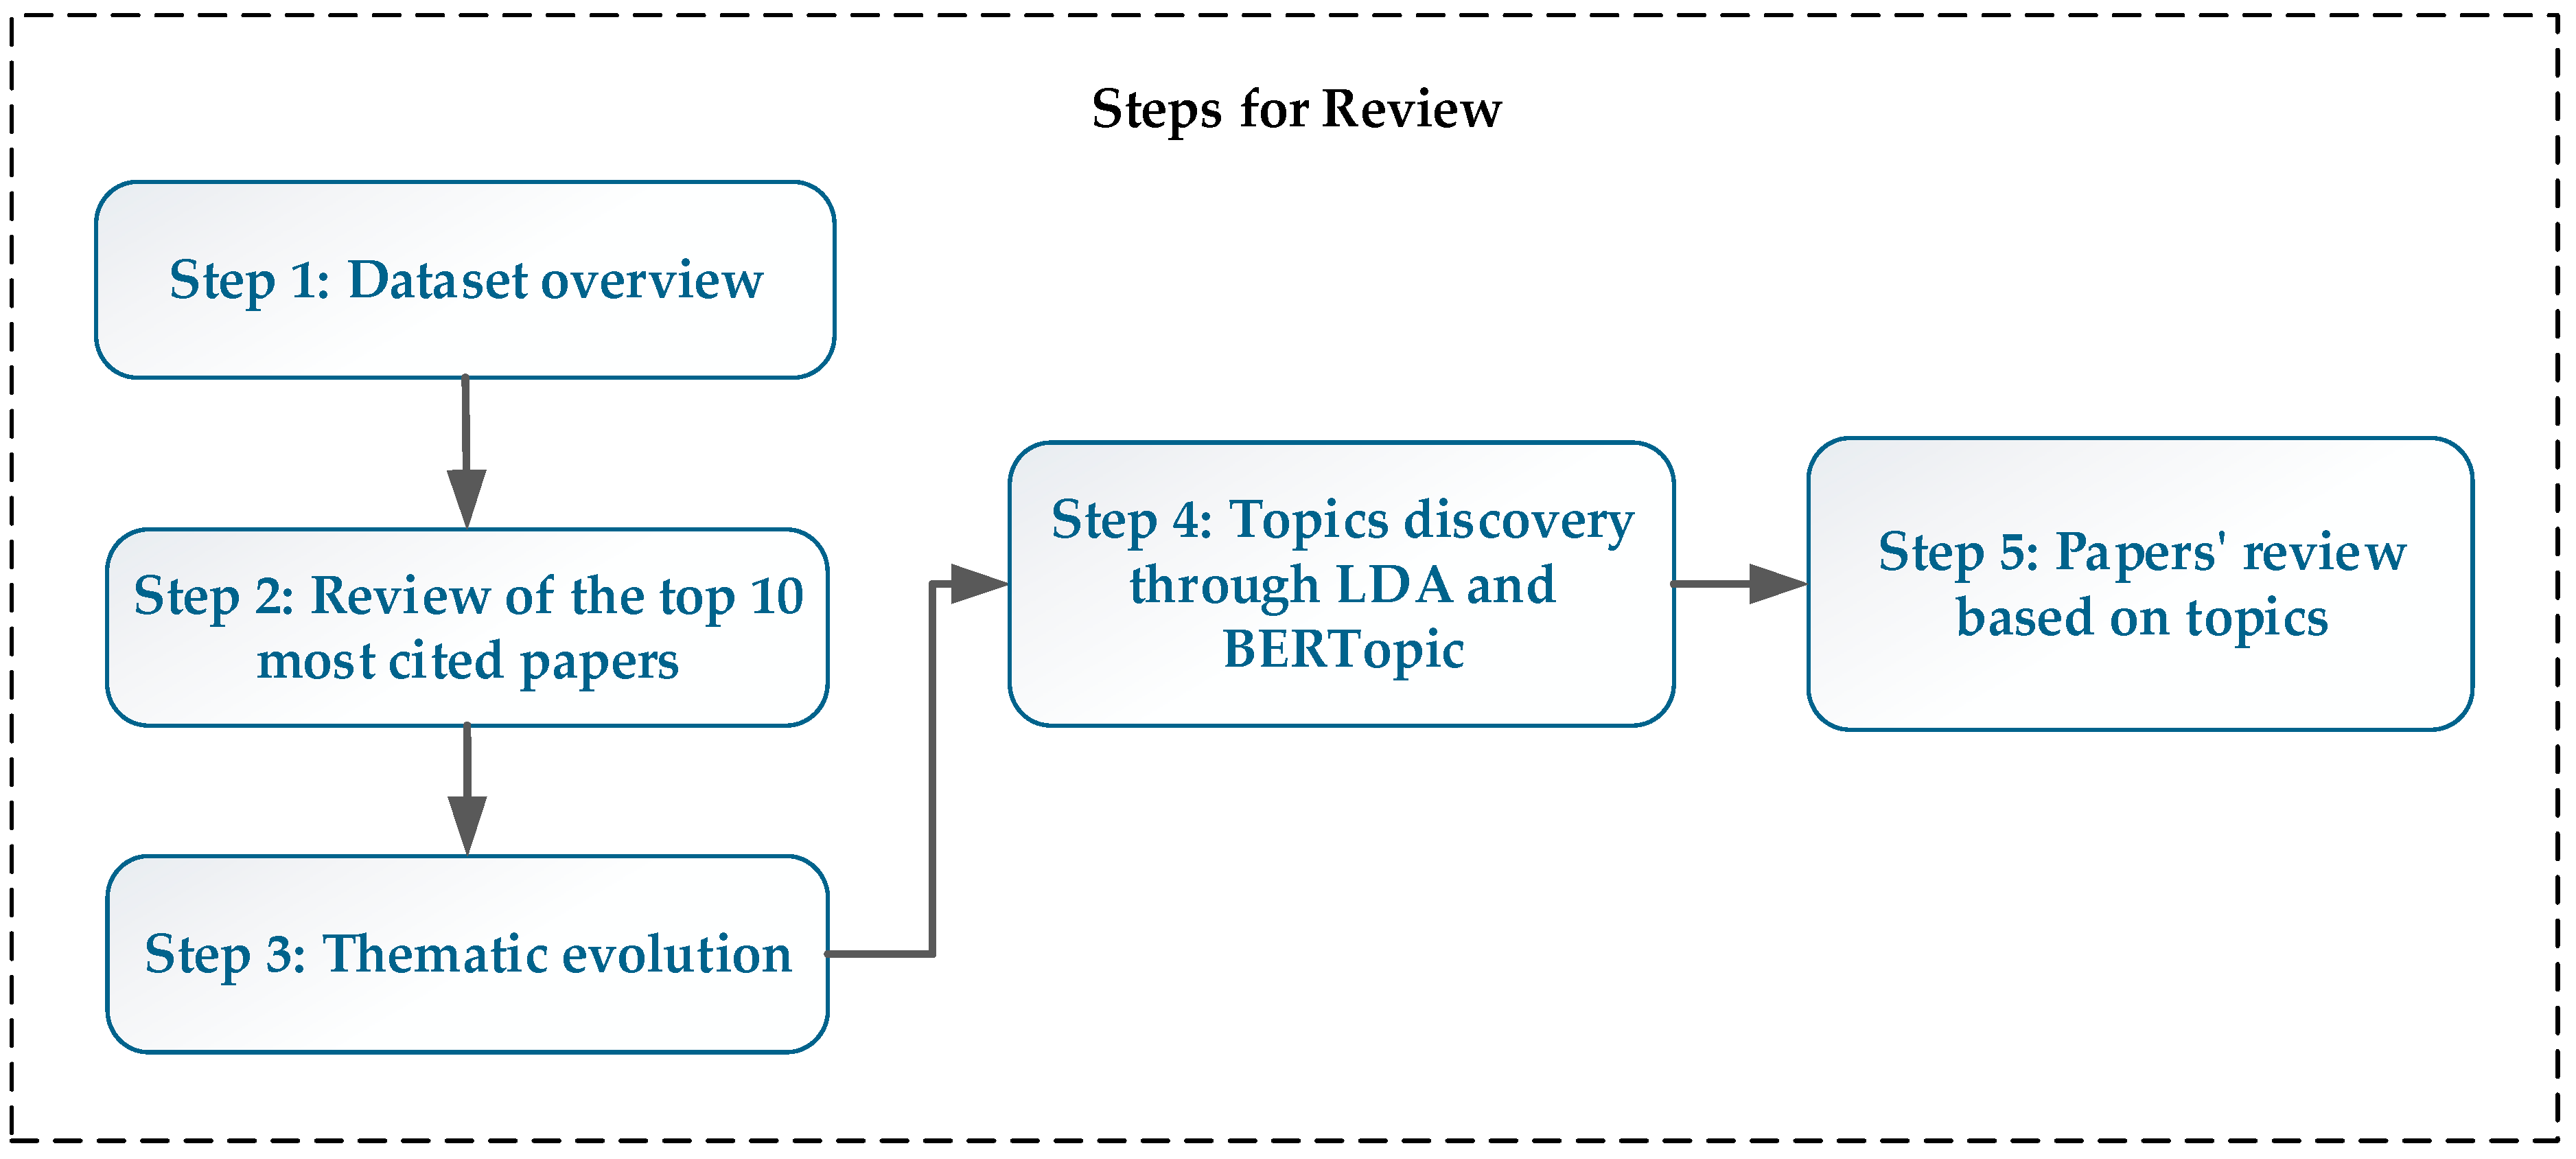
For the systematic review, the steps are provided in Figure 2.
The dataset overview step is dedicated to highlighting some of the key elements related to the dataset used for the analysis and review. As a result, a series of bibliometric-specific analyses are provided, such as time span, sources, number of documents, annual growth rate (%), average years from publication, average citations per document, number of co-authors per document, number of references, number of Keywords Plus, and number of authors’ keywords. While most of the analyses can be easily understood due to their suggestive names, a particular focus should be given to the Keywords Plus [33] analysis. It should be mentioned that Keywords Plus are a particular type of keyword that is extracted by the database from the references of the papers included in the dataset, being the most frequent terms in the bibliographic references. This feature is specific to the database used in the paper, and it provides more information (in addition to the classical authors’ keywords analysis) related to the papers used by the authors of the articles included in the dataset as sources for their papers.
Step 2 focuses on the top-10 cited articles. These papers are analysed in terms of the number of authors, total citations (TC), total citations per year (TCY), and normalised total citations (NTC). The NTC indicator is highly dependent on the extracted dataset, and it shows how many times a paper has succeeded in gaining more citations than the average number of citations obtained by the paper published in the same year as the paper under analysis [34]. After the brief discussion related to papers and their characterising indicators in terms of citations, a review of the top-10 most-cited papers is provided for the purpose of offering a first view of the field.
Step 3 is dedicated to the identification of the themes associated with the papers in the extracted dataset. A series of thematic maps is built in Biblioshiny [35] by using either authors’ keywords and bigrams in titles. Additional analyses, such as trend topics based on bigrams in titles, co-occurrence networks with respect to the bigrams in titles, and Keywords Plus, are provided for the purpose of better shaping the research field. For cross-checking the results, other scientometric tools, such as VOSviewer and CiteSpace, were involved.
Step 4 deals with topic discovery based on LDA and BERTopic.
Topic analysis was conducted using both LDA and BERTopic. LDA is a generative probabilistic model used primarily for topic modelling in natural language processing (NLP) that is used for discovering hidden (also known as “latent”) topics within a given corpus [34,36]. The analysis has considered, for each paper, the title and the abstract. To improve the performance of the topic modelling, a preprocessing pipeline was applied. As a first step, the text was converted to lowercase, the punctuation was removed, and the general English stop words were included in the Gensim Python package 4.4.0. Additionally, since LDA treats tokens such as “GST” and “grey systems theory” as separate entities, term normalisation was also performed to provide a unified representation for semantically equivalent expressions. Subsequently, domain-specific stop words, such as the ones used as filters during the paper selection process, were also removed. Lemmatisation was applied using the spaCy library with the en_core_web_lg pipeline to convert inflected or derived words into their canonical forms. Finally, bigrams and trigrams were constructed using Gensim’s Phrases class to capture frequently co-occurring terms, as these multi-word expressions often carry important semantic meaning. For the LDA model, a grid search approach has been applied for choosing the best values for the alpha and eta parameters, with the aim of balancing a relatively low number of topics and a high coherence score. The LDA implementation used in this study is the one provided by the Gensim Python library [37].
BERTopic extracts a coherent topic representation through the development of a class-based variation in TF-IDF, providing competitive results when compared to a series of benchmarks in topic modelling [38]. In order to enhance the topic detection accuracy, the textual data has been preprocessed first by converting the text to lowercase. Furthermore, the minimum size of the clusters and the minimum samples parameter of the HDBSCAN algorithm have been iteratively adjusted to achieve a similar balance between granularity and interpretability.
After running both analyses, the results of the LDA are put in connection with the ones obtained from BERTopic in order to properly extract the research topics.
Starting from the topics discovered, in step 5, a review is provided for the area of grey clustering, highlighting the main advancements made in these areas.

4. Results

This section presents the results obtained for the extracted dataset, and it follows the structure depicted in Figure 2.

4.1. Dataset Overview

Main information about the data is presented in Table 2. The dataset consists of 318 documents, published in 159 distinct sources, within a considerable chronological frame (1989–2024). It is noticed that scientists tend to publish their papers about grey clustering methods and applications in a limited set of journals oriented towards this domain of research, a hypothesis validated by the fact that the number of sources is exactly half of the number of articles.
The dataset exhibits a pronounced geographical bias, with a large proportion of publications originating from China. This reflects the country’s significant research activity in grey systems theory, which was expected due to the fact that grey systems theory was first introduced in Nanjing, China, and later on has expanded to other countries and territories. On the other hand, this situation also triggers potential country-level and citation-network biases. Such concentration should be considered when interpreting thematic patterns and collaboration structures, as it may amplify regional research priorities while underrepresenting global diversity.
The research contributions’ novelty is demonstrated by the value recorded for the average years from publication indicator (6.8), while other metrics further highlight the relevance of the field, its high importance and impact within the academic community: average citations per document (12.29) and count of references (9292).
The increased degree of collaboration in conducting research about grey clustering methods and applications is evidenced by the co-authors per document indicator’s value (3.65 scientists per document on average). This demonstrates that the articles from the dataset are the result of several authors’ contributions from all over the world, which ensures enhanced visibility both nationally and internationally, as well as an improvement in the overall quality of the research outcomes due to the diversity of perspectives and expertise.
The annual growth rate of 10.78% proves not only the domain’s expansion but also the active research involvement and consistent effort of academics.
Table 3 is focused on two important indicators, analysed with the intention of offering readers a deeper understanding of the extracted manuscripts’ content: Keywords Plus and the author’s keywords. The interdisciplinary vision of the field is proven by the significant difference between the two indicators, the author’s keywords (1059) being more than double compared to the number of Keywords Plus (450).
The value of 1.42 reflects the numerical ratio between the Keywords Plus (450) and the documents from the dataset (318), confirming that the extracted manuscripts have a compact and concentrated vocabulary.
The standard number of keywords per manuscript is 3.33, and it was recorded as the average between the author’s keywords (1059) and articles included in the investigation (318).
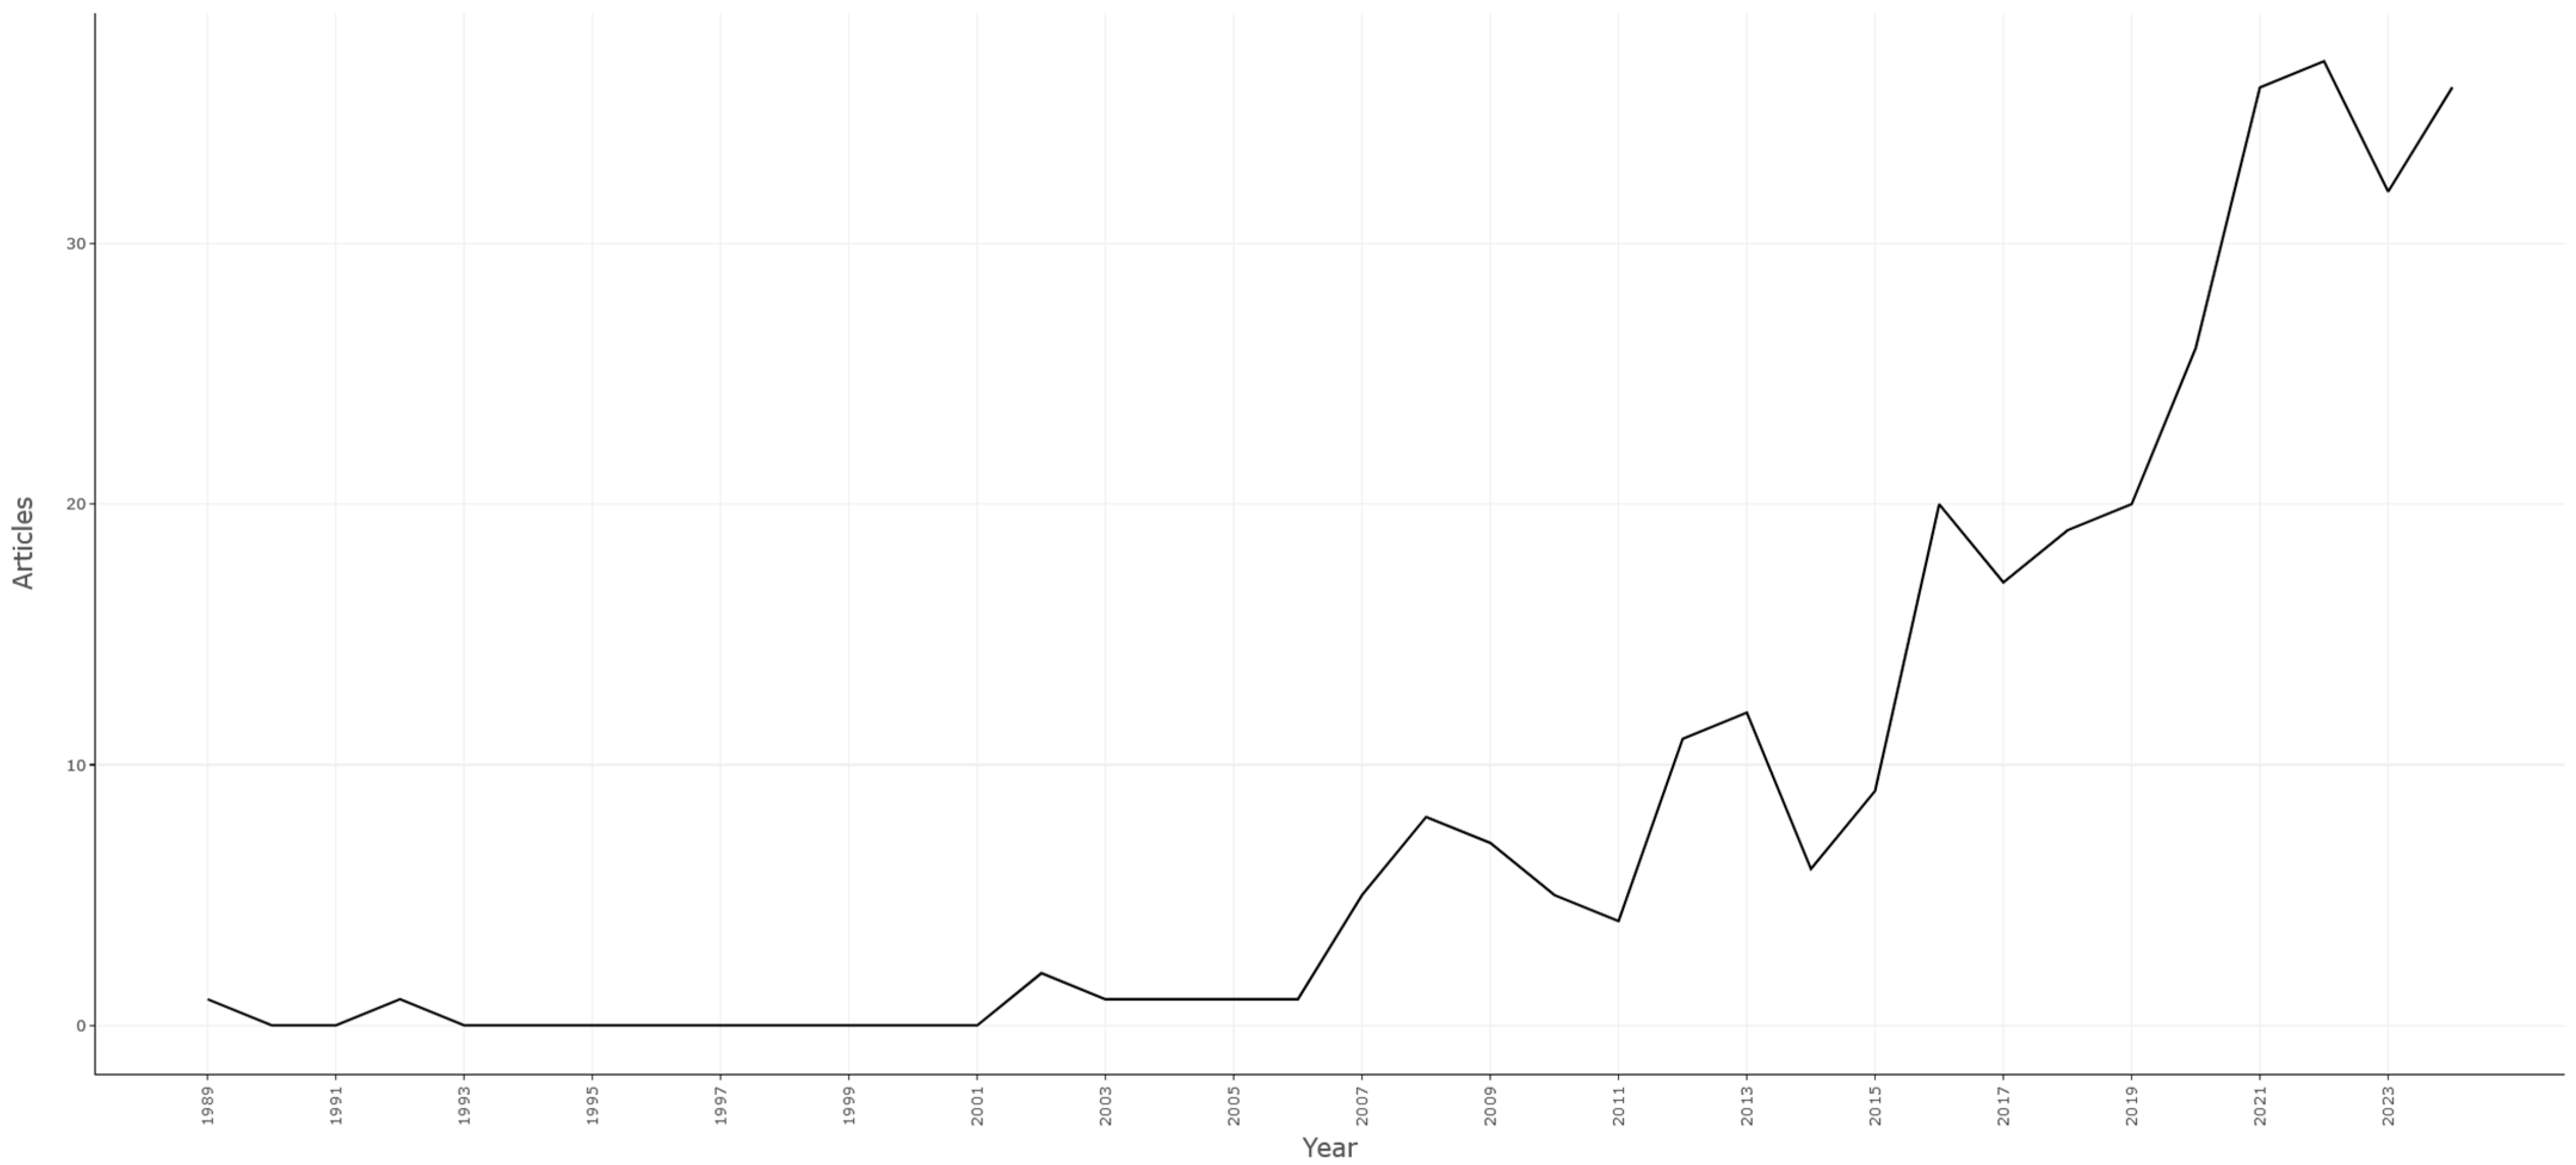
Figure 3 illustrates the evolution of the yearly scientific production through a graphical representation. The importance of the domain within the scientific community and the academics’ significant interest is proven by the annual growth rate (10.78%).
As noted in the image below, the trend is predominantly upward with small fluctuations throughout the analysed timestamp. As for a better understanding of the field’s evolution, three main periods can be delimited. The first one is represented by the interval between 1989 and 2001, which is characterised by an extremely low, almost non-existent scientific production—only a single article was published in each of the following two years: 1989 and 1993. The second phase, which covers the period between 2002 and 2014, is marked by a moderate evolution of the field, with occasional cycles of growth and decline, reaching a maximum of 12 papers in 2013. Lastly, starting in 2015, there is a visible, significant increase in the number of publications about grey clustering methods and applications, which can be attributed to the technological progress, growing interest in addressing complex problems under uncertainty, and even to the expanded applicability of these techniques and methods in domains of considerable relevance (e.g., healthcare, sustainability, finance).
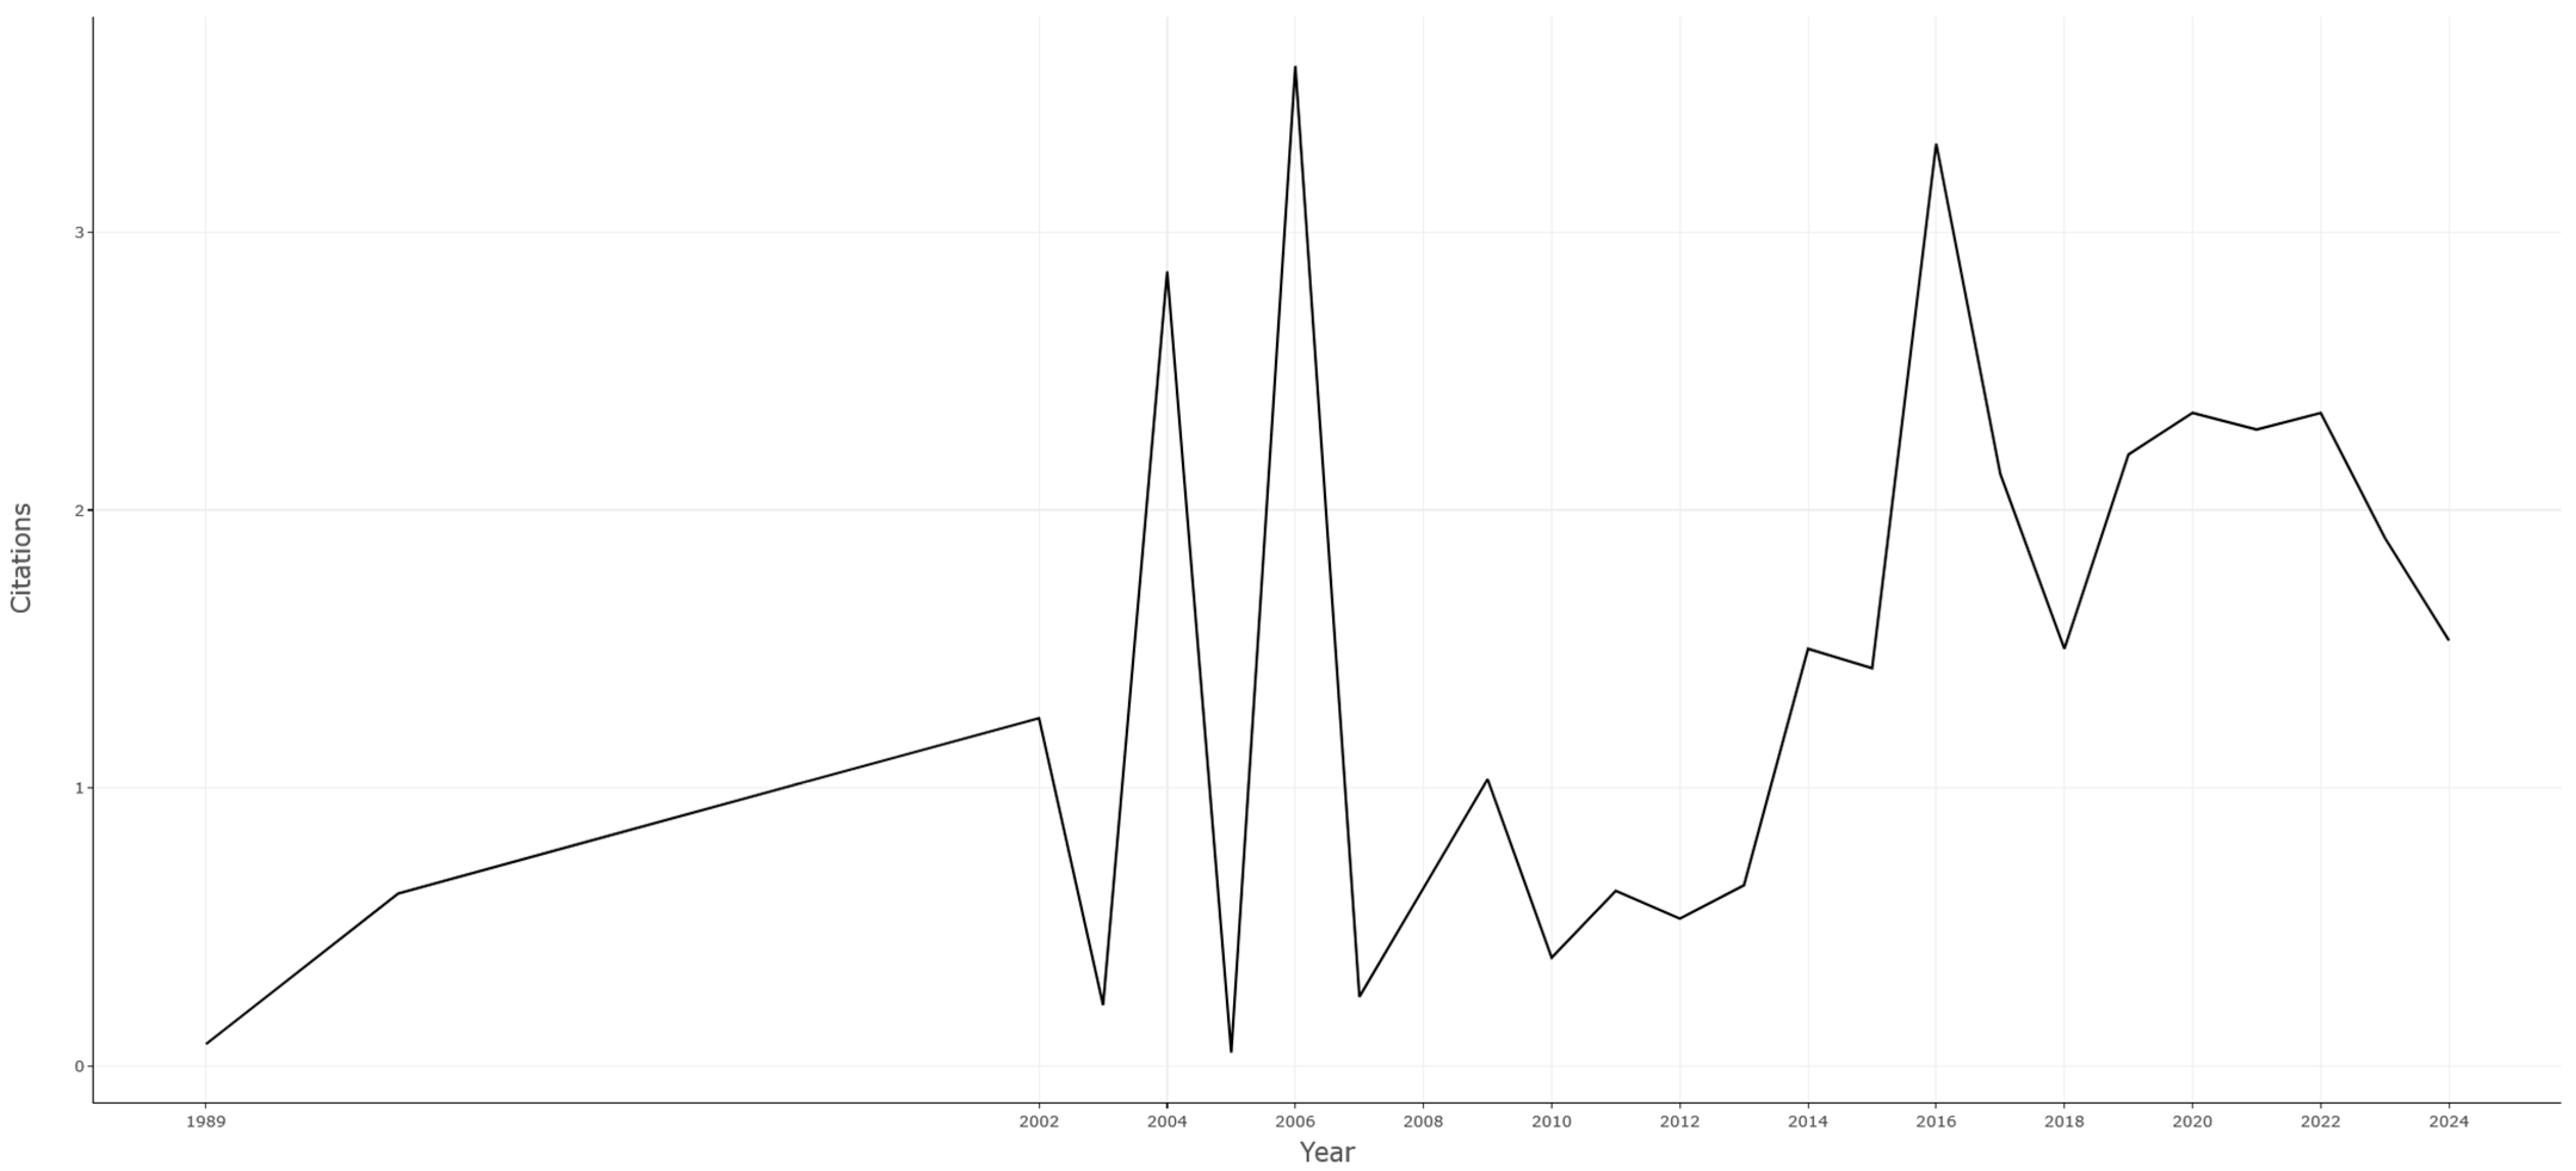
Figure 4 presents the yearly mean citations evolution.
According to the illustration, the trend is unstable, marked by successive increases and decreases, without a consistent pattern, caused by the manuscripts’ fluctuating impact in the scientific community over time.
Furthermore, the extreme values of the average citations recorded in certain periods (e.g., 0.2 in 2003 vs. 2.9 in 2004 vs. 0 in 2005 vs. 3.6 in 2006) indicate that some articles were more influential in terms of citations compared to others from the field.
This irregular behaviour complicates the prediction of the articles in a long-term context, and it is caused by external factors such as the topics’ popularity, research findings’ visibility, themes addressed’ applicability, readers’ interest, etc.

4.2. Review of the Top-10 Most-Cited Papers

The purpose of this section is to review the top-10 most-cited papers related to grey clustering methods and applications from the extracted set of data.
Being divided into two distinct stages, this investigation will uncover the topics with the highest impact within the scientific community, identify the research trends, recognise influential contributors, and guide future research.
The overview of the papers listed in the hierarchy will be presented in the first phase, with a focus on the general details about the articles, authors, and journals, and their impact in the academic literature, by investigating important citation indicators (total citation—TC, total citations per year—TCY, normalised total citations—NTC).
The following phase is oriented towards the actual review of the manuscripts. For each publication, the theme addressed, the data used for the investigation, along with the main results, findings, and future research directives, are presented. This will help readers better understand the contribution of this paper to the domain’s evolution, assess the strengths and limitations of the used methodologies, and even uncover current gaps and areas that require future exploration.

4.2.1. Top-10 Most-Cited Papers—Overview

The top-10 articles about grey clustering methods and applications, with respect to the number of citations recorded, are listed in Table 4.
Regarding citations, it is noticed that the total citations (TCs) indicator ranges between 339 and 66, the total citations per year indicator (TCY) varies from 33.90 to 3.60, while the normalised total citations indicator (NTC) falls within 10.66 and 1.00. The first paper written by Delgado and Romero [39] holds the leadership position only in the case of the first two indicators (TC = 339, TCY = 33.90, NTC = 10.23), followed by the manuscripts written by Jiskani et al. [40] (TC = 110, TCY = 22.00, NTC = 9.59) and Sahoo et al. [41] (TC = 107, TCY = 10.70, NTC = 3.23).
For more details, please inspect Table 4.

4.2.2. Top-10 Most-Cited Papers—Review

A brief description of the top-10 most-cited articles’ content is presented in Table 5. Each of the manuscripts included in the hierarchy will be reviewed, with focus on the topic addressed, data used, main findings, results, and future work directives.
The first position in the ranking is occupied by the paper belonging to Delgado and Romero [39], which is oriented towards investigating the mining project in Peru, with a focus on the environmental conflict analysis, involving the so-called IGCEW, an integrated method that combines both grey clustering and entropy-weight. The case study used data collected through field interviews, which consisted of various structured questionnaires, and involved three main stakeholder groups: 115 individuals from the urban environment, 105 individuals from the rural environment, and 35 specialists. In this process, seven criteria were taken into consideration, namely GDP per capita, employment level, poverty rate, healthcare access, school enrollment, crime rate, and drinking water access. The results showed that the mining project was seen by the urban population as beneficial, since new jobs, income, and opportunities would appear, while in the rural environment, people held unfavourable opinions, as they were worried about factors such as poverty, water, agricultural damage, etc. The specialists had a neutral opinion. According to this examination, the main factors that highlighted contrasts between urban and rural environments were GDP per capita, poverty, employment, and drinking water access. This paper offers an efficient, low-cost method for investigating environmental conflicts, which can contribute to fields’ expansion and even support authorities in decision-making processes. As for future work, the scientists discuss validating the IGCEW method in other contexts, and for simplifying the data processing step, a computer system’s implementation is recommended.
The following manuscript belongs to Jiskani et al. [40] and discusses a new framework used for assessing the green and climate-smart mining (GCSM), helpful for companies and policymakers, as it can identify the current situation, possible challenges, risks and future priorities. In terms of data, the authors used statistical data from the Chinese open-pit mining industry, technical experts’ assessment for each of the indicators, considering two perspectives (reality and desirability), and structured indicator framework (six main categories: Environmental Protection, Pollution Control, Waste Management, Energy and Resource Efficiency, Technology Enablement and Implementation, Sectoral and Managerial Efficiency). The methods used were fuzzy analytic hierarchy process (AHP) and grey clustering, and the findings demonstrate that the performance of the indicators was low in reality, but high in desirability. This uncovers a significant gap between the current practice and the actual needs that are required for sustainable mining. As for future work directives, some ideas would be the following: framework improvements, its constant and continuous evaluation, involvement of authorities and stakeholders, comparative investigations across countries, decision support system’s development, etc.
Sahoo et al. [41] developed and evaluated a model based on grey analytic hierarchy process (grey-AHP) for identifying the zones marked by environmental vulnerability in a region in India. The mentioned methodology implied thirteen factors (grouped into three main categories: natural, environmental, and human) from satellite, geographic information system, climatological, and conventional/field data. The Environmental Vulnerability Index (EVI) was used to classify the regions into four distinct levels, namely low, moderate, high, and extreme, while grey-AHP combined structured weighting with grey clustering and handled uncertainty, proving a moderate level of reliability of the map classification. The results showed that northern areas are more environmentally vulnerable, and a strong relationship between EVI and elevation was noticed. For future work directives, it is recommended to further apply the methodology to other regions and compare the outcomes.
The article written by Lu et al. [42] is about developing and testing a framework for large-scale group decision-making in social networks (LSGDM-SN). The purpose of this initiative is to improve the decision-making processes by estimating the values that are missing or incomplete in hesitant fuzzy preference relations (HFPRs) and by addressing distrust behaviours. The authors involved in their manuscript sought experts’ opinions and also tested the method using a real case scenario, related to street-stall businesses, focused on a location in China, more specifically, Nanjing. The results proved the efficiency of the grey clustering algorithm in grouping decision makers in distinct subsets, a fact that reduced the complexity considerably. The involvement of opinion difference and reference risk had a positive impact on evaluating the HFPRs’ missing values. The distrust behaviours were split into different levels (acceptable, general, serious), which helped in defining new strategies and improved consensus indices. When discussing the case study’s outcomes, the framework made a great contribution in choosing the optimal stall site (KINGMO shopping centre). In terms of future work directives, the authors highlight the need to further extend the HFPRs, explore other types of decision makers’ behaviours, consider leadership influence, and test the framework’s performance in other case studies, too.
Lin et al. [43] discussed in their paper a new method based on grey clustering analysis (GCA), which aims to overcome the traditional artificial intelligence approaches’ limitations and the current challenges for incipient fault detection in oil-immersed transformers. A large dataset was collected from 1400 TCP transformers, and a case study for the Taiwan Power Company was involved. The GCA used whiten-weight functions for dealing with uncertain and limited data, and it divided the faults into nine distinct categories. The findings demonstrated that for Taiwan transformers, the method accurately detected overheating problems and partial discharge defects in the case of a foreign case study (Australia). In terms of performance, the method was compared to fuzzy logic and artificial neural networks and proved its effectiveness, being simpler, faster, and even more accurate. For future work directives, it is recommended to implement GCA in online systems and consider real-time monitoring tools.
Ke et al. [44] are oriented towards urban ecological security, more specifically, on exploring the ecological risks and spatial patterns through an evaluation framework. The research is focused on 16 cities from China (Hubei Province) and aims to provide improved strategies for urban development. The data covers the period between 2007 and 2016, gathered from multiple sources, and focuses on 26 indicators, according to the DPSIR model (Driver Pressure State Impact Response). The weights are computed using Principal Component Analysis (PCA), the grey clustering method is utilised for evaluating the ecological security in an uncertain context, while spatial analysis is used for examining spatial correlation and clustering patterns. The results showed that the average ecological security index value was medium to good, and southwest cities were better compared to the northeast ones in terms of ecological security. The period before 2014 uncovered a weak correlation, while after that year, the cities started to influence each other significantly. Apart from these, it is proven that government actions and efficient policies directly influence the improvement of environmental safety. For future work, the authors suggest a further focus on predicting next trends in the sector and on improving collaboration among cities. A list of policy recommendations is provided at the end of the article, based on the issues discovered in each region.
The article belonging to Tsai et al. [45] is about developing a CAD (computer-aided design) system which aims to assist designers in predicting consumers’ perception about products’ image, taking into consideration factors such as form and colour. In order to test the system’s efficiency, the authors utilised a case study about an electronic door lock. The dataset involved 330 form samples, 125 colour variations, and 225 form–colour combinations. The participants were 40 students who rated the samples on a scale (female, male, neutral). Methods such as fuzzy neural network and grey theory were used, and the findings showed that colour has a stronger impact, when compared to form, on influencing individuals’ perception about a specific product. The new CAD system eases designers’ work through powerful functions and an intuitive interface, and for future research directives, the authors recommend further applying the system to other product category types, exploring additional factors, and also developing reverse search.
The scope of the research written by Tajesh [46] is to identify and rank the key barriers encountered in the supply chain sector, and, at the same time, assist managers in handling and combating the current challenges and vulnerabilities in the field. Based on in-depth research, 30 essential barriers were uncovered, and a real case study about an Indian electronics manufacturing firm was included. The grey clustering technique helped in grouping and filtering the barriers in distinct clusters, the VIKOR method offered a plan for decision-making, with focus only on the most important barriers, and the sensitivity analysis demonstrated that the results were solid and unbiased. This research can assist managers and authorities in better understanding the challenges in the supply chain field, prioritising them correctly and improving the overall process by the adoption of more efficient strategies. As for future work directives, the author suggests taking into consideration more barriers, case studies from real life, and developing an automated evaluation tool.
In their paper, Li et al. [47] discuss the ecological security (ES) aspects. With the intention of identifying the key factors that influence ES, they focused on 35 districts and counties in the Pearl River Delta urban area (China). The data was collected from numerous sources, and indicators related to socioeconomic, natural environment and landscape ecology were considered. The authors conducted a robustness investigation and compared 20 methods in order to uncover the most stable results for ES, which was obtained in the case of complex correlation coefficient and grey clustering. Applied to the case study, the results proved that in the regions of central and eastern Pearl River Delta, the lowest level of ecological security was registered, in western regions, the level was medium, while in inland zones, the level was strong. Moreover, the BP-DEMATEL model was involved for mapping cause-effect associations between indicators, highlighting that the total value of ecosystem services is the fundamental factor. The study is important for the ecological sector, especially today when numerous challenges arise along with technological advancement and an increasing population in urban areas. For future work directives, the authors suggest further improving the capacity of the ecological service, urban green infrastructure, focusing on enhanced strategies and polices, and even testing and comparing the framework’s results in other urban regions.
The last paper found in the hierarchy belongs to Zhu et al. [48]. The authors developed a hierarchical clustering technique, based on a 3D grey correlation degree, which aims to understand the connections and differences among decision makers, split them into correct subgroups and identify the core decision maker. In order to accomplish this, 15 experts who made decisions with respect to five distinct assessment indicators were involved. For each expert, a decision matrix and a reciprocal/complementary judgement matrix were provided. For determining the maximum and minimum correlation within classes, a heuristic algorithm was utilised, and the proposed method’s results proved that the large groups of decision makers were correctly split into subgroups, and a representative expert for each group was correctly selected. It was also demonstrated that the current approach outperformed the traditional methods, and for future research perspectives, the authors recommend further extending the proposed method and applying it to multi-stage decision-making processes.
To better understand the content of the papers, a methodological quality assessment for the top-10 most-cited papers was also conducted, while the results can be observed in the column positioned on the right side of Table 5. The methodological category of the papers was assigned with respect to the type of data used, as follows:
  • Empirical (involves real-world data);
  • Simulation-based (involves simulated/synthetic/model-generated data);
  • Theoretical (new theoretical models, with more focus on theory than on validation).
This examination helps in evaluating the maturity of each research and identifying scientists’ writing tendencies in the most-cited manuscripts from the field. Overall, it is noticed that most of the papers, more specifically, eight out of ten, are classified as empirical studies. This distribution suggests that grey clustering research is currently driven by real-world applications and case-based validation, which indicates an increasing level of practical engagement with the method. At the same time, only one paper falls into the simulation-based category and one into the theoretical category, reflecting the relatively limited number of works focused on formal methodological development compared to application-oriented studies. The observed pattern in the selected papers can be interpreted as an indication of its current orientation and developmental stage, where empirical adoption is progressing rapidly while theoretical formalisation remains an ongoing area for future work.
Based on the findings uncovered for each paper, a cross-study evaluation can also be conducted.
First of all, it was noticed that most of the manuscripts listed in the hierarchy combined grey clustering with other advanced techniques (analytic hierarchy process, multi-stage decision frameworks, fuzzy logic, neural networks, etc.) and demonstrated their high efficiency and accuracy when applied in various areas, such as environment, sustainability, green practices, industry and engineering applications, decision-making, and risk analysis.
Moreover, it was remarked that there is an increased interest in risk evaluation, especially in domains where data is unclear or incomplete (environment, industry, ecology).
There were also observed challenges associated with data (e.g., the lack of validation in dynamic/temporal contexts), and the reliance on datasets collected mainly from China. A strong geographic concentration is uncovered, which is reflected in the results of multiple analyses. The field is not evenly represented worldwide, as Chinese studies dominate the dataset, and due to the large number of papers published from that region, the field tends to look more mature than it is. Because the research output from other countries in the domain is significantly lower, there is a high possibility of missing them. It is important to understand and be aware of this regional concentration and citation habits because they can completely influence the bibliometric results.
Going further with the discussion, the increasing complexity of today’s unpredictable situations demonstrates the need to integrate grey clustering into more intelligent decision systems.
Furthermore, in terms of methodological limitations observed across the top-cited papers, it has been noted as a strong dependence on case-specific datasets, as there are many studies that validate their results based on single-region data, which reduces the generalisability of the obtained results. Also, it has been noticed that there are few papers that assess how whitening weight functions, membership thresholds, or indicator weightings influence results, which can be better addressed in future studies in this area.
Nevertheless, as mentioned before, most of the studies rely on cross-sectional datasets, even in contexts where underlying phenomena (e.g., environmental vulnerability, energy production, ecological security) evolve over time. In these cases, it can be underlined that the modelling process is rather static, even though it might have also been approached from a dynamic point of view, leaving places for further studies.
Other limitations of the selected studies are related to the need for more theoretical justification for the use of hybrid models, better traceability of how the inputs propagate through clustering outputs, or the presence of benchmark comparisons.
Also, in terms of cross-paper inconsistencies, one can notice differences in the creation of the weights used in the analysis, differences in the treatment of uncertainties—there are authors that are working with interval grey numbers, while others are using the crisp indicator values, or in the evaluation metrics.
Despite the cross-papers inconsistencies and the observed methodological limitations, it should be mentioned that the top-cited papers have shaped the trajectory of grey clustering research in several ways, starting from establishing hybrid models as the dominant paradigm, positioning grey clustering as a practical tool in various research fields, or providing empirical validation which supports the use of grey clustering in future studies into real-world situations. Given all these, the most-cited papers in the extracted dataset have laid the foundation for subsequent theoretical and methodological developments.
All these insights contribute to a better understanding of grey clustering application in real-life scenarios, uncover current trends, research gaps, and future research directives and ideas.

4.3. Thematic Evolution

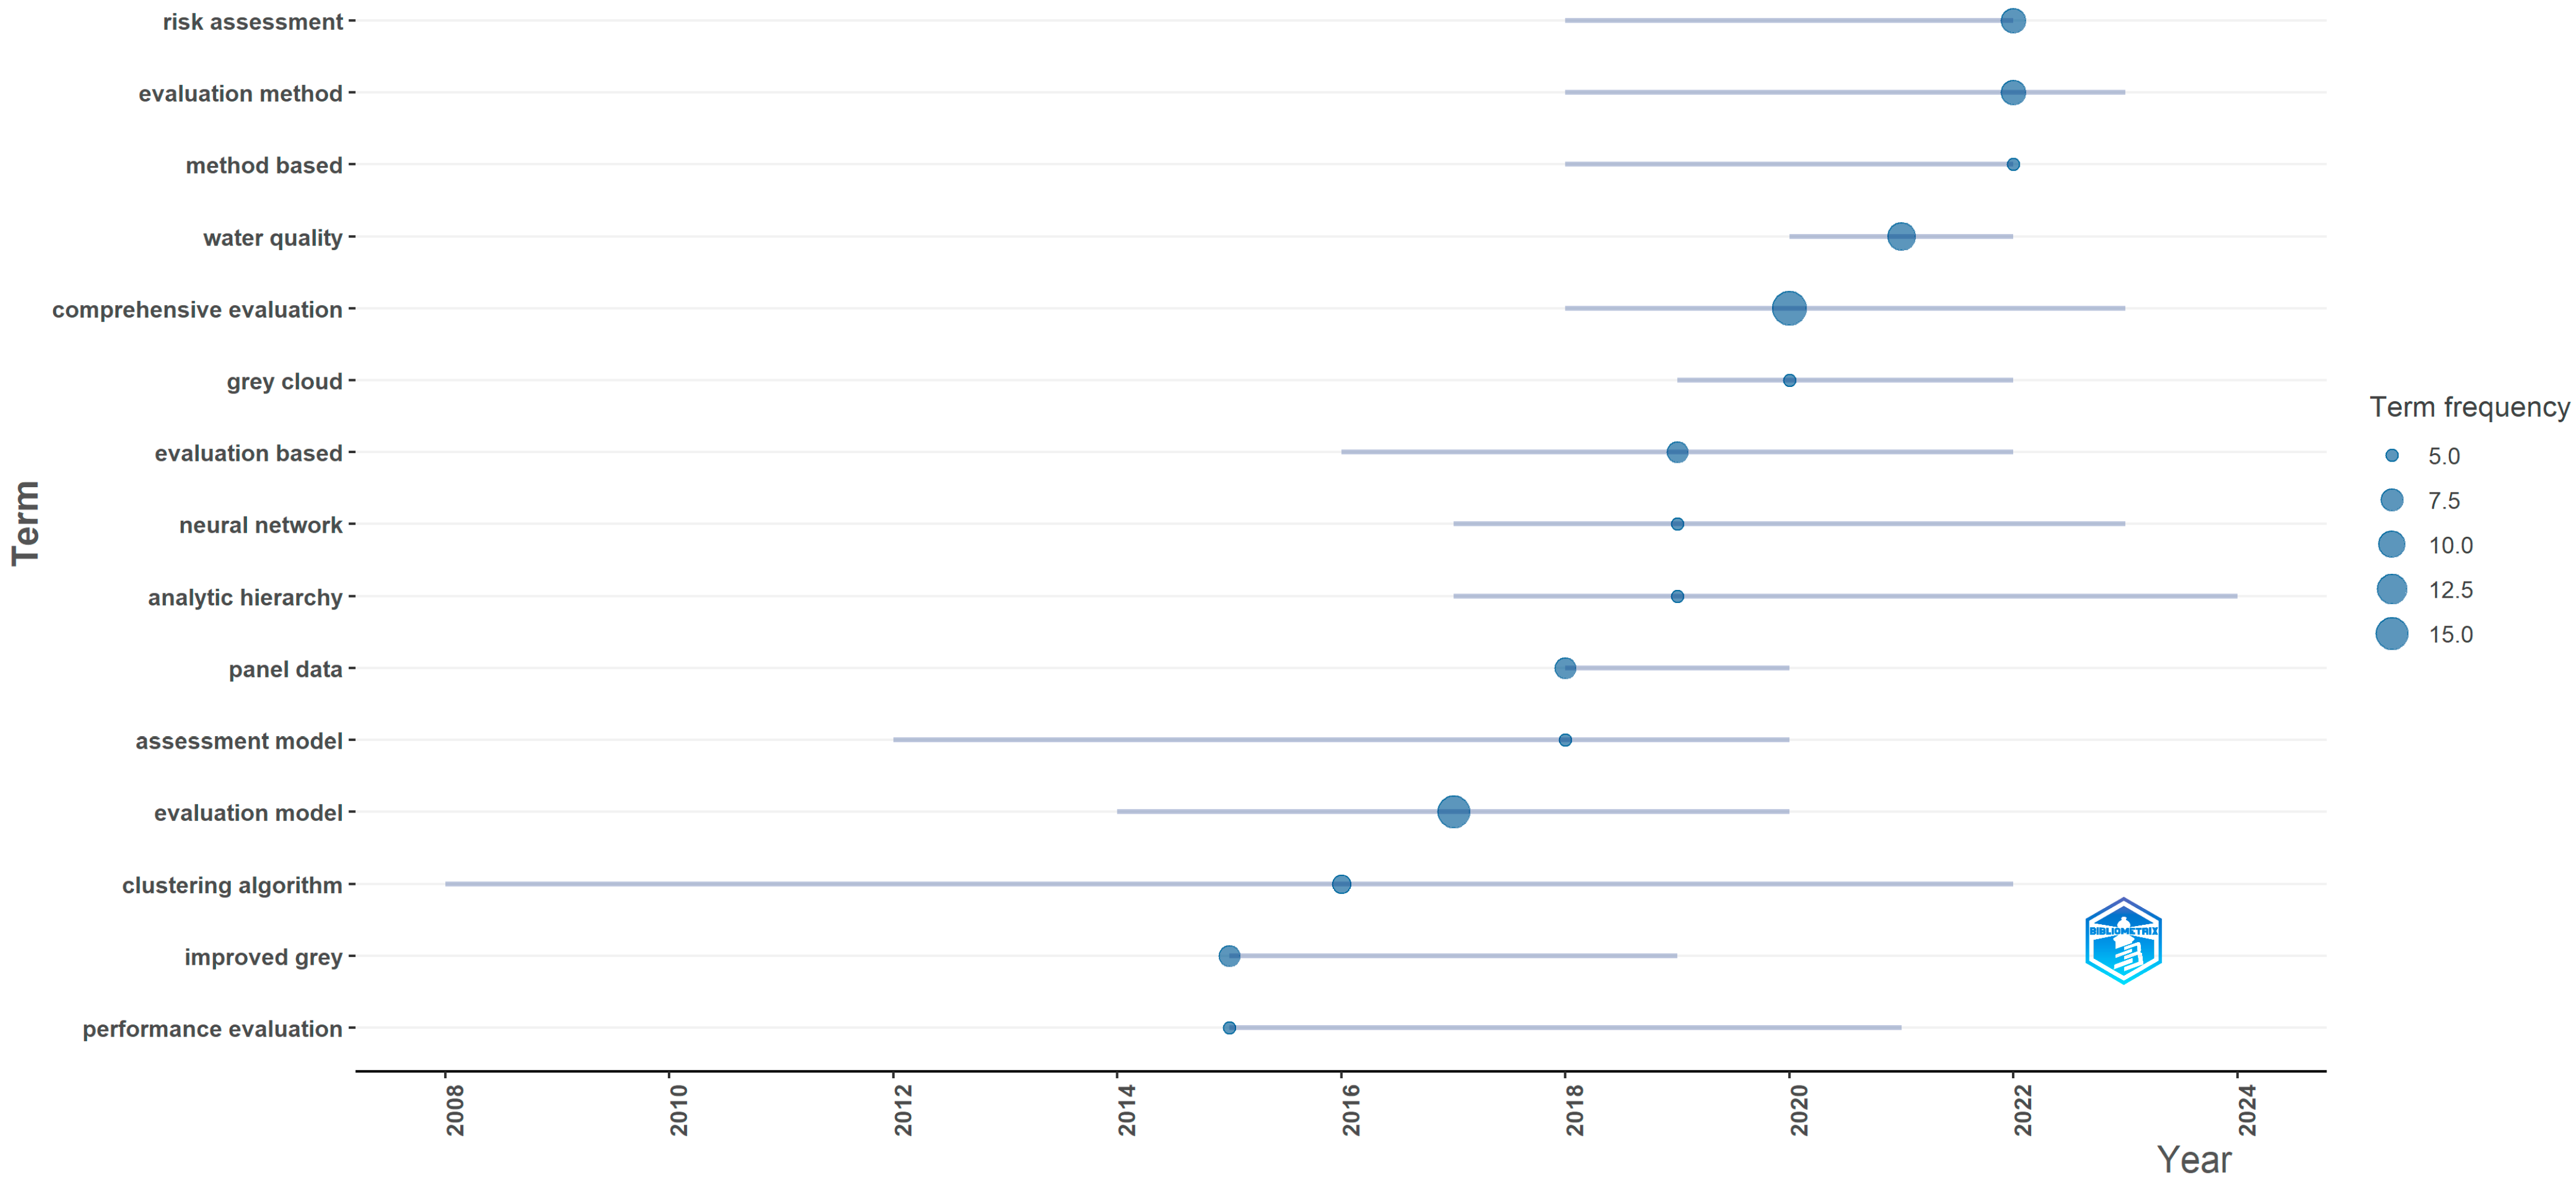
The trend topics based on bigrams in titles are presented in Figure 5. For generating the below graph, the following collection of words was excluded: grey cluster, gray clustering, grey system, clustering analysis, grey clustering, clustering evaluation, model-based, clustering model, clustering approach, clustering method, grey systems, and cluster analysis. The approach of eliminating the mentioned bigrams is justified by the fact that these terms’ frequency is very high, and it is already known that the selected set of articles refers to grey clustering methods and applications. Thus, the scope of this examination was to find out the areas of applicability and the techniques involved.
The identified bigrams uncover various evaluation methods, techniques, and applications in distinct fields, which can help authorities make informed decisions and propose efficient strategies.
Some of the terms (e.g., risk assessment, evaluation method, method-based, comprehensive evaluation, evaluation-based, assessment model, evaluation model, performance evaluation) are related to guiding decisions, measuring results, identifying, and managing risks.
Concepts like water quality refer to environmental monitoring, public health, and resource management, while bigrams such as grey cloud, neural network, analytic hierarchy, clustering algorithm, and improved grey represent data analysis tools and methodologies for working with large datasets, useful for prediction, performance evaluation, and statistical analysis.
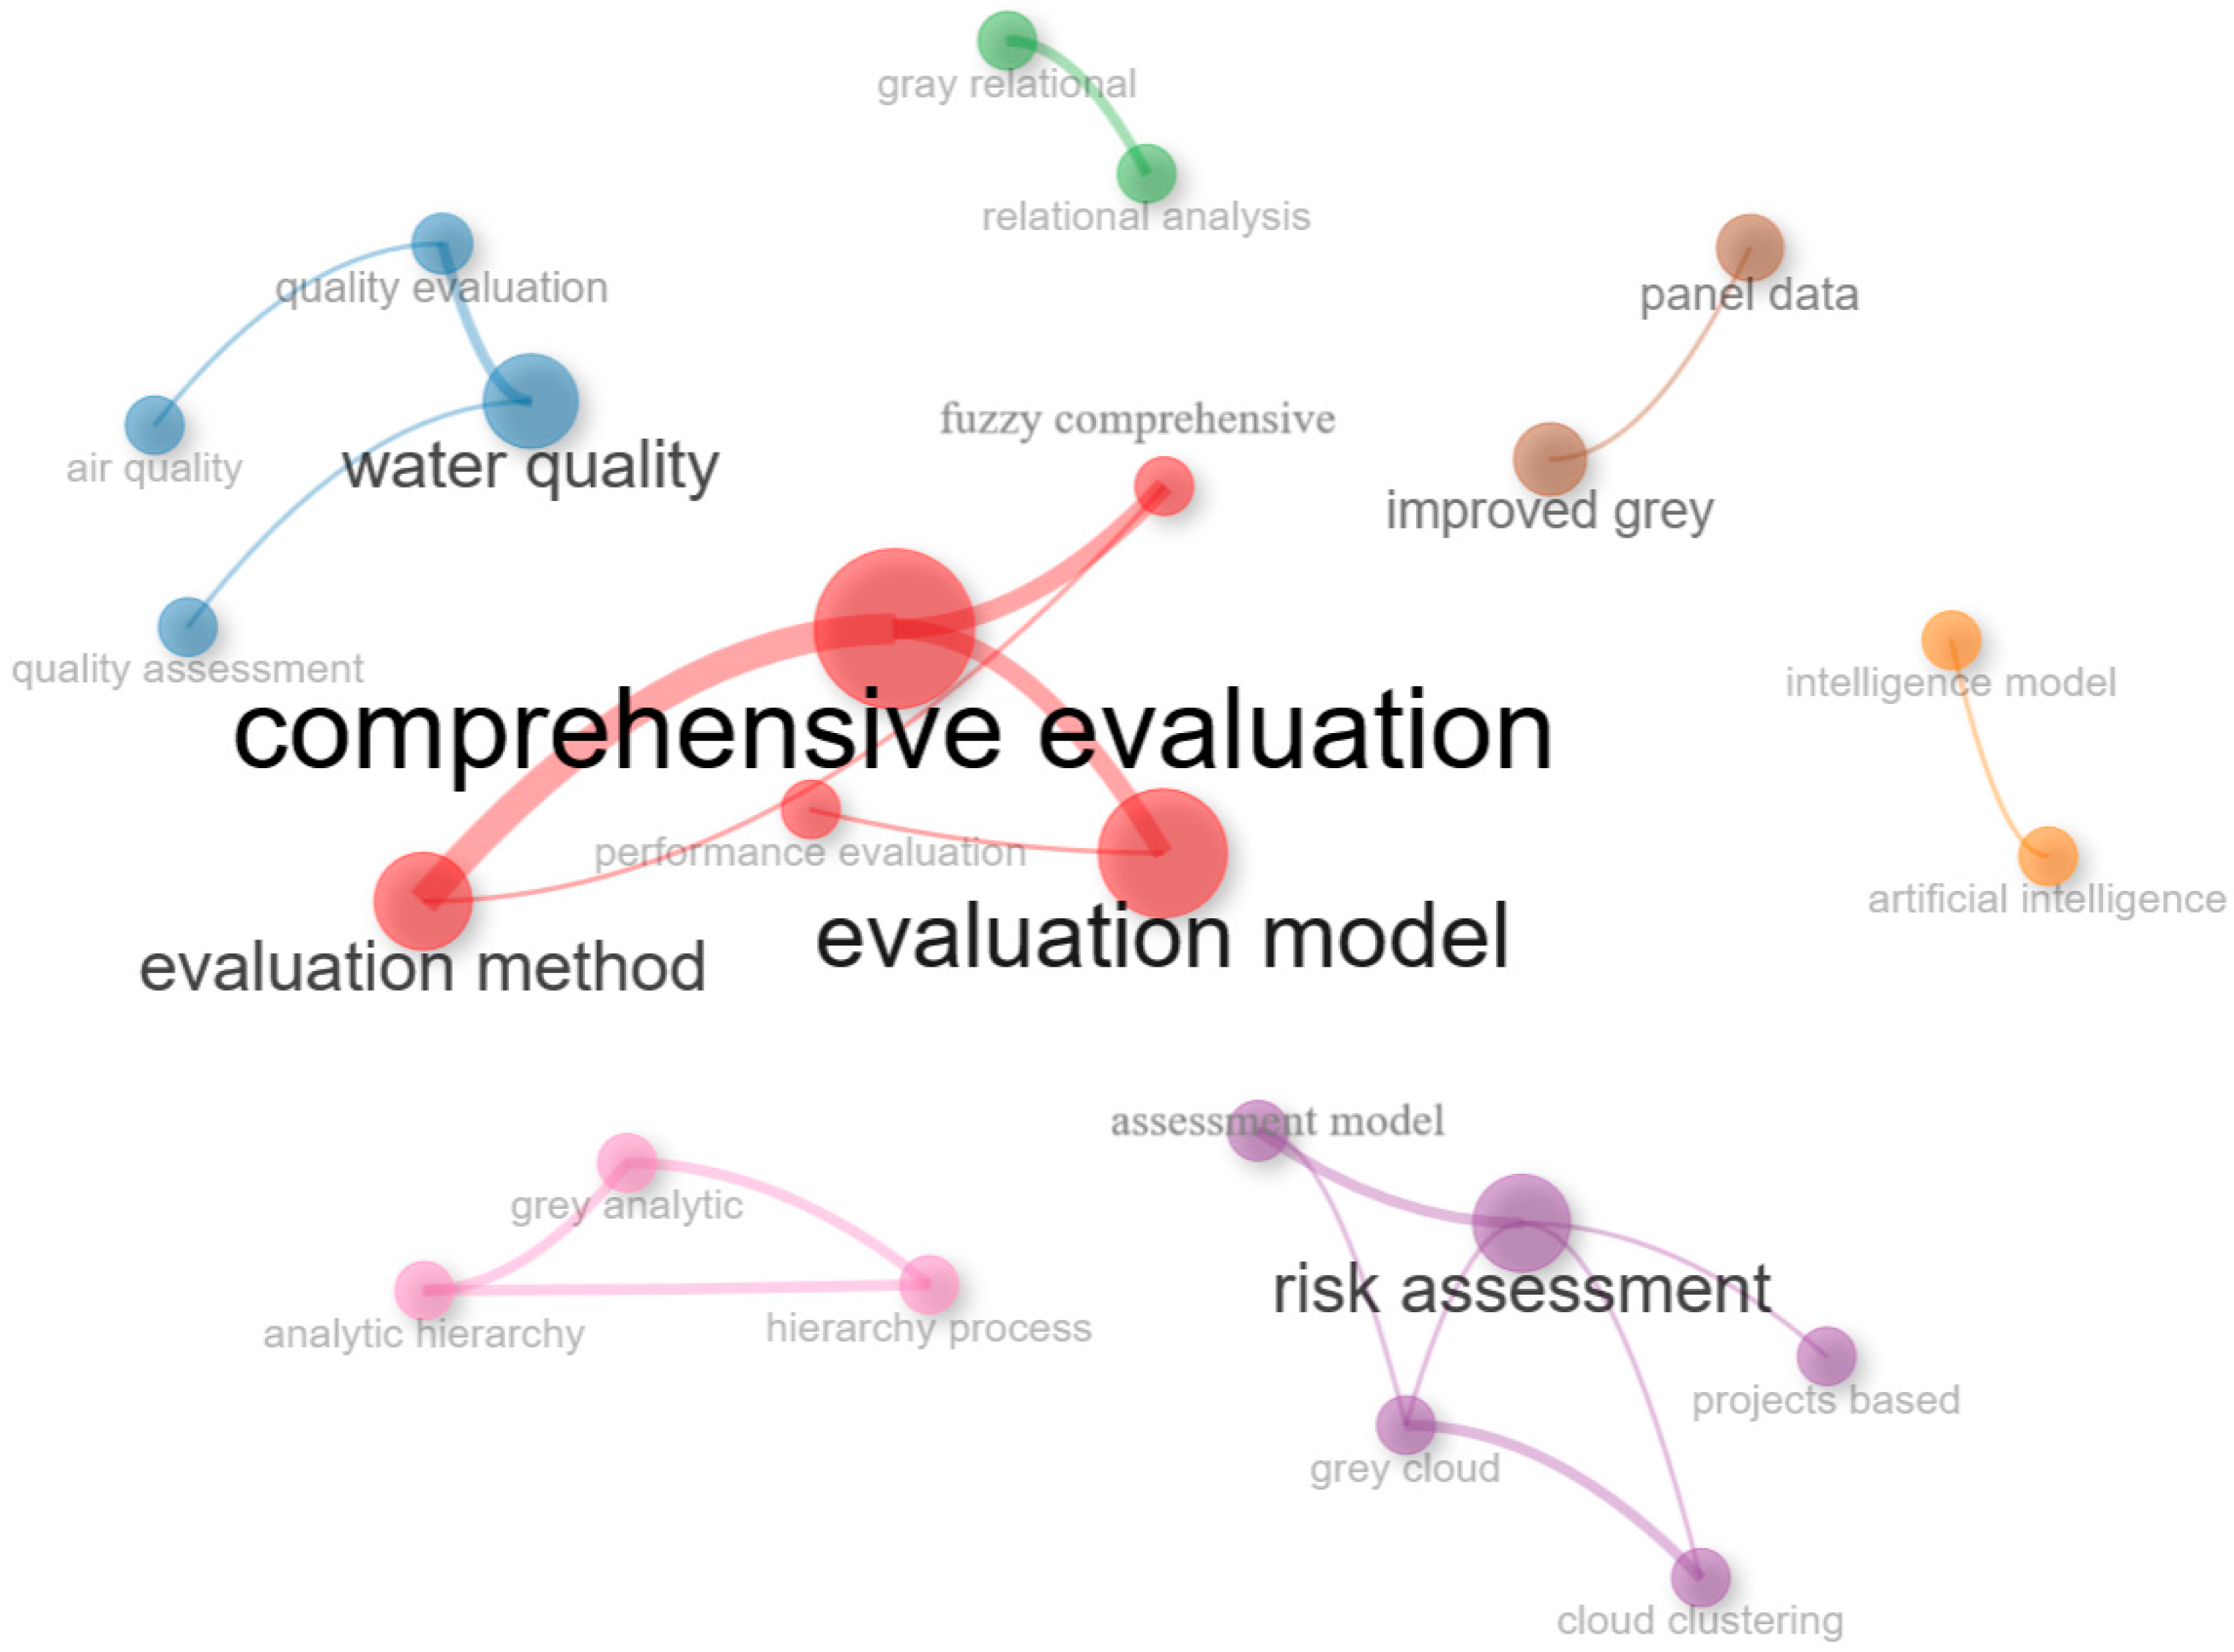
Figure 6 represents a co-occurrence network for bigrams in titles. In line with the same rationale discussed in Figure 5, when the below image was created, the following terms were excluded: grey cluster, gray clustering, grey system, clustering analysis, grey clustering, clustering evaluation, model-based, clustering model, clustering approach, clustering method, grey systems, and cluster analysis.
Based on the visual illustration, seven distinct clusters are delimited, as follows:
  • First cluster (blue): water quality, air quality, quality evaluation, and quality assessment.
It highlights the efficiency of grey clustering in assessing the environmental indicators under uncertainty (air, water).
  • Second cluster (green): grey relational and relational analysis.
It includes the names of two methods useful for studying how various indicators are connected to one another in cases when data is incomplete or partially known.
  • Third cluster (brown): panel data and improved grey.
The two bigrams included in this cluster are, in general, used together to provide efficient temporal patterns’ assessment, interdependencies between variables, and even trends’ evaluation, in uncertainty contexts.
  • Fourth cluster (red): comprehensive evaluation, evaluation model, evaluation method, performance evaluation, and fuzzy comprehensive evaluation.
The terms included in this cluster are related to various evaluation methodologies used for assessing the quality or performance of complex data/systems.
  • Fifth cluster (orange): intelligence model and artificial intelligence.
This cluster refers to the power of artificial intelligence in enhancing grey clustering methods, such as contributing to a better classification of indicators under uncertainty and optimising the handling of large volumes of data.
  • Sixth cluster (purple): risk assessment, assessment model, grey cloud, project-based, and cloud clustering.
The terms included in this cluster refer to risk assessments in project-based environments, involving techniques such as grey clustering and grey cloud for handling complex or incomplete data, testing the accuracy, and predicting problems.
  • Seventh cluster (pink): hierarchy process, grey analytic, and analytic hierarchy.
The methods included in this cluster are useful in structuring complex decisions, comparing results from different alternatives, and prioritisation in case of uncertain data.
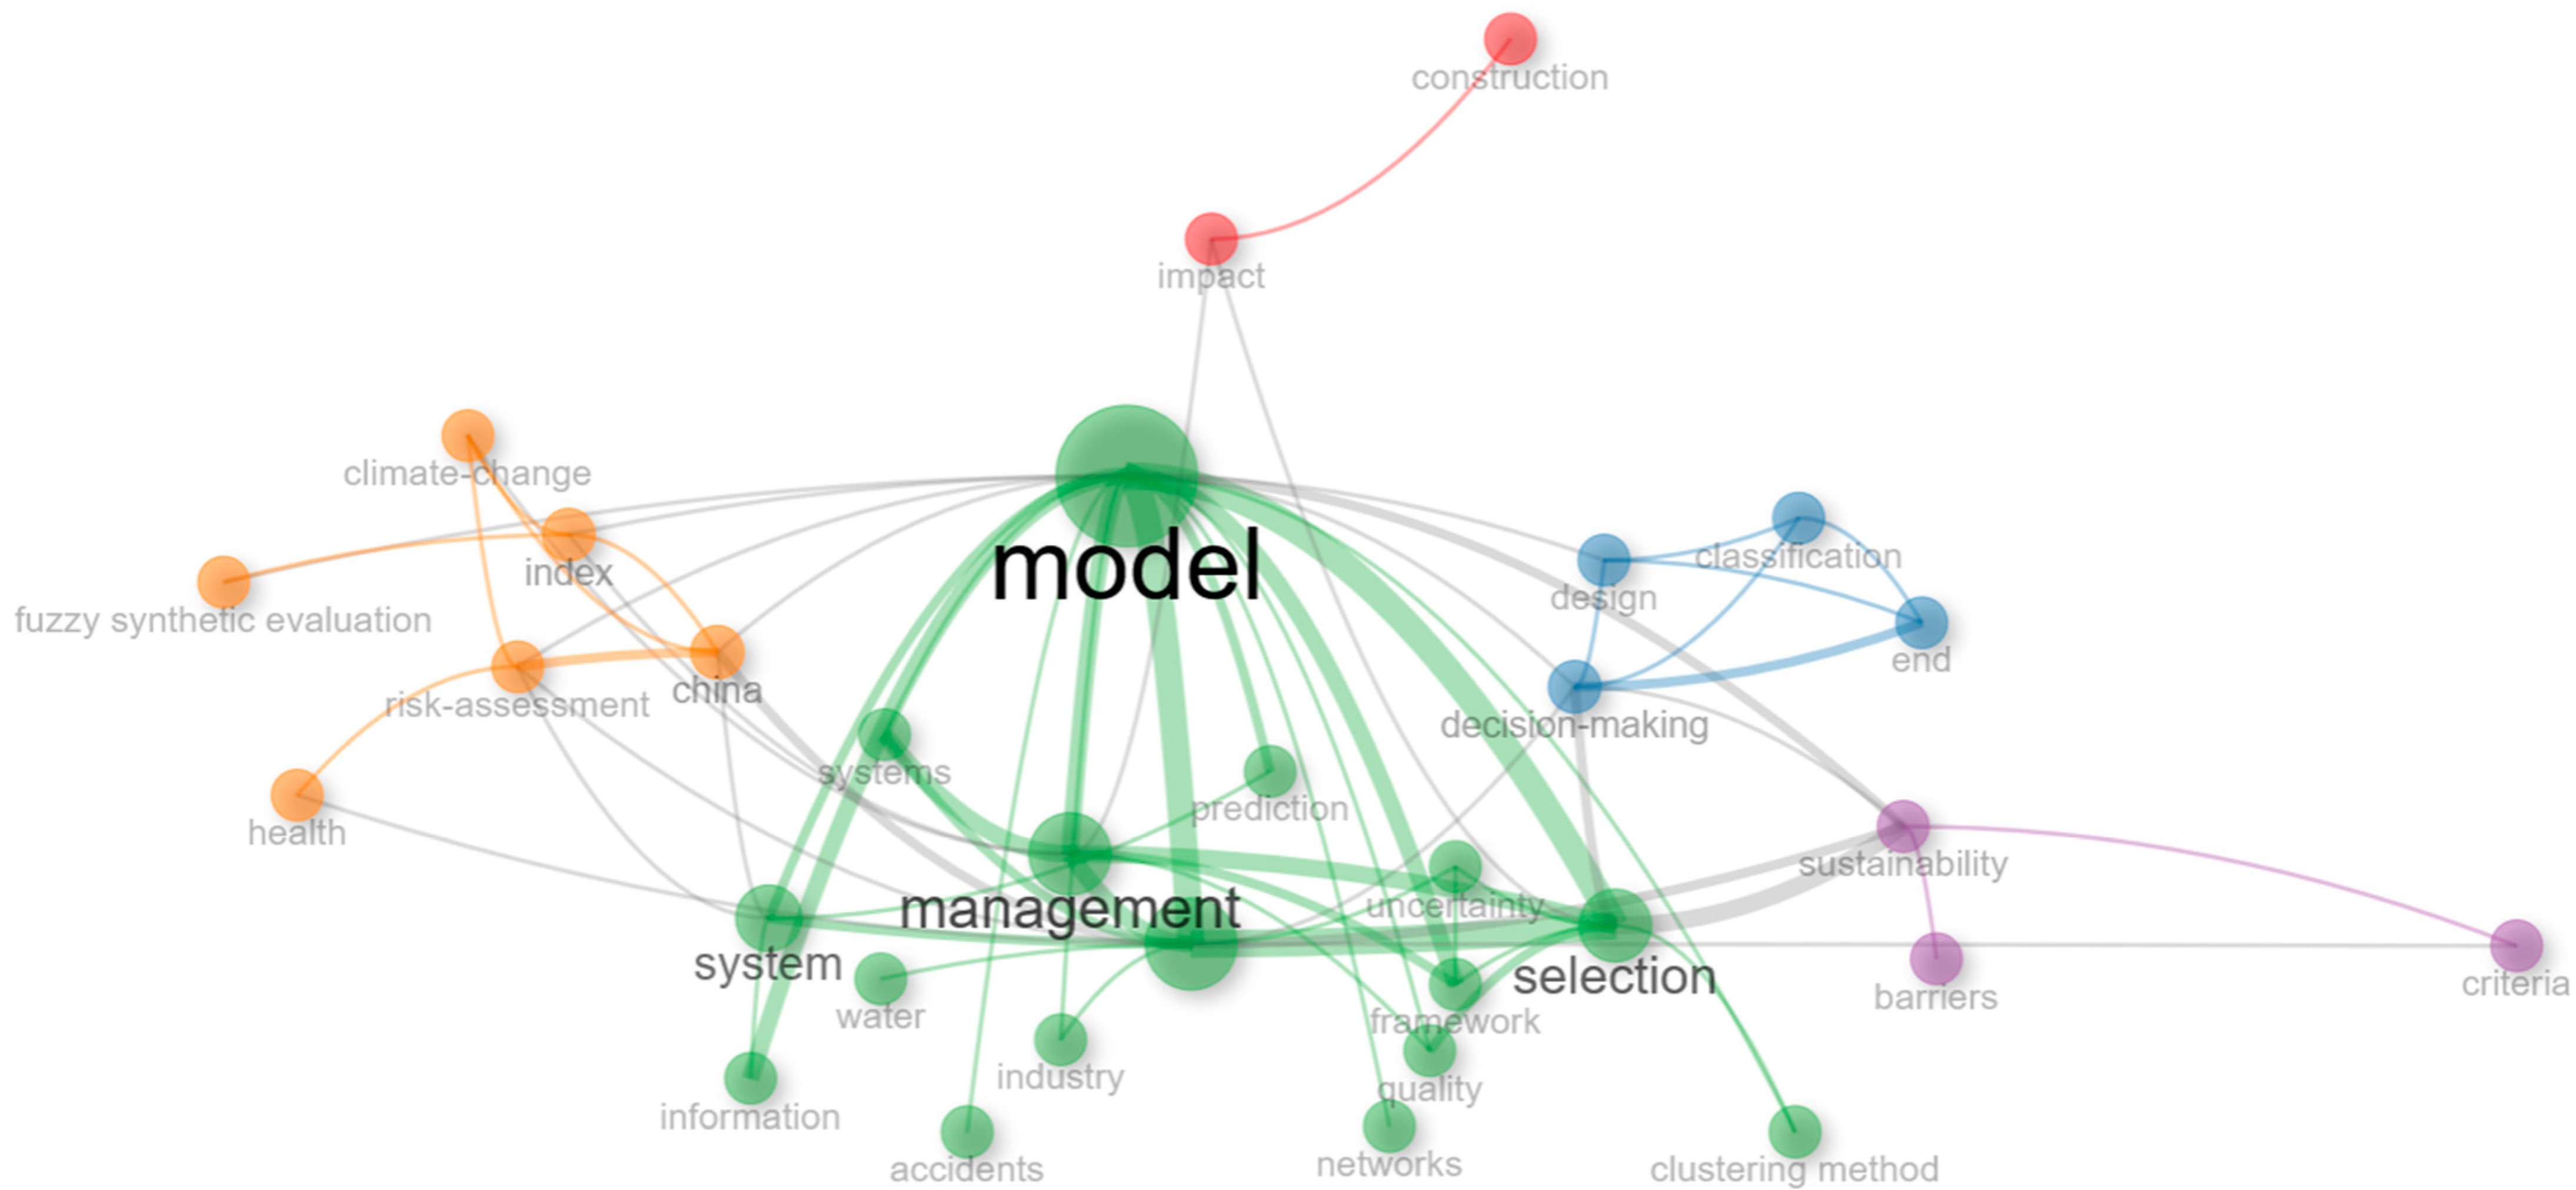
Figure 7 captures another co-occurrence network, this time focused on Keywords Plus. The following clusters were delimited:
  • First cluster (red): construction and impact.
This cluster highlights the power that the grey clustering method has on the construction sector, including but not limited to risk assessment (e.g., costs, delays, etc.), decision-making under uncertainty, performance evaluation, environmental impact, etc.
  • Second cluster (blue): decision-making, design, classification, and end.
This cluster underlines the use of grey clustering in decision-making processes, especially in the design phase, helping in factor classification, and leading to the end results.
  • Third cluster (purple): sustainability, criteria, and barriers.
Another sector in which grey clustering has a considerable impact is represented by sustainability, as it assists in evaluating different factors, identifying barriers and challenges encountered in achieving the environmental and social goals.
  • Fourth cluster (green): model, systems, prediction, uncertainty, selection, clustering method, framework, quality, networks, management, system, water, information, industry, and accidents.
This cluster is about involving grey clustering in distinct systems and making predictions in uncertainty contexts, as it has a considerable power in managing the quality and selecting the most suitable decisions and strategies in domains associated with environment, network, safety, risk, and accidents.
  • Fifth cluster (orange): index, China, climate change, fuzzy synthetic evaluation, risk-assessment, and health.
This cluster refers to fuzzy synthetic evaluation for risk assessment, with a particular focus on understanding the relationship between climate change and people’s health in big countries, such as China.
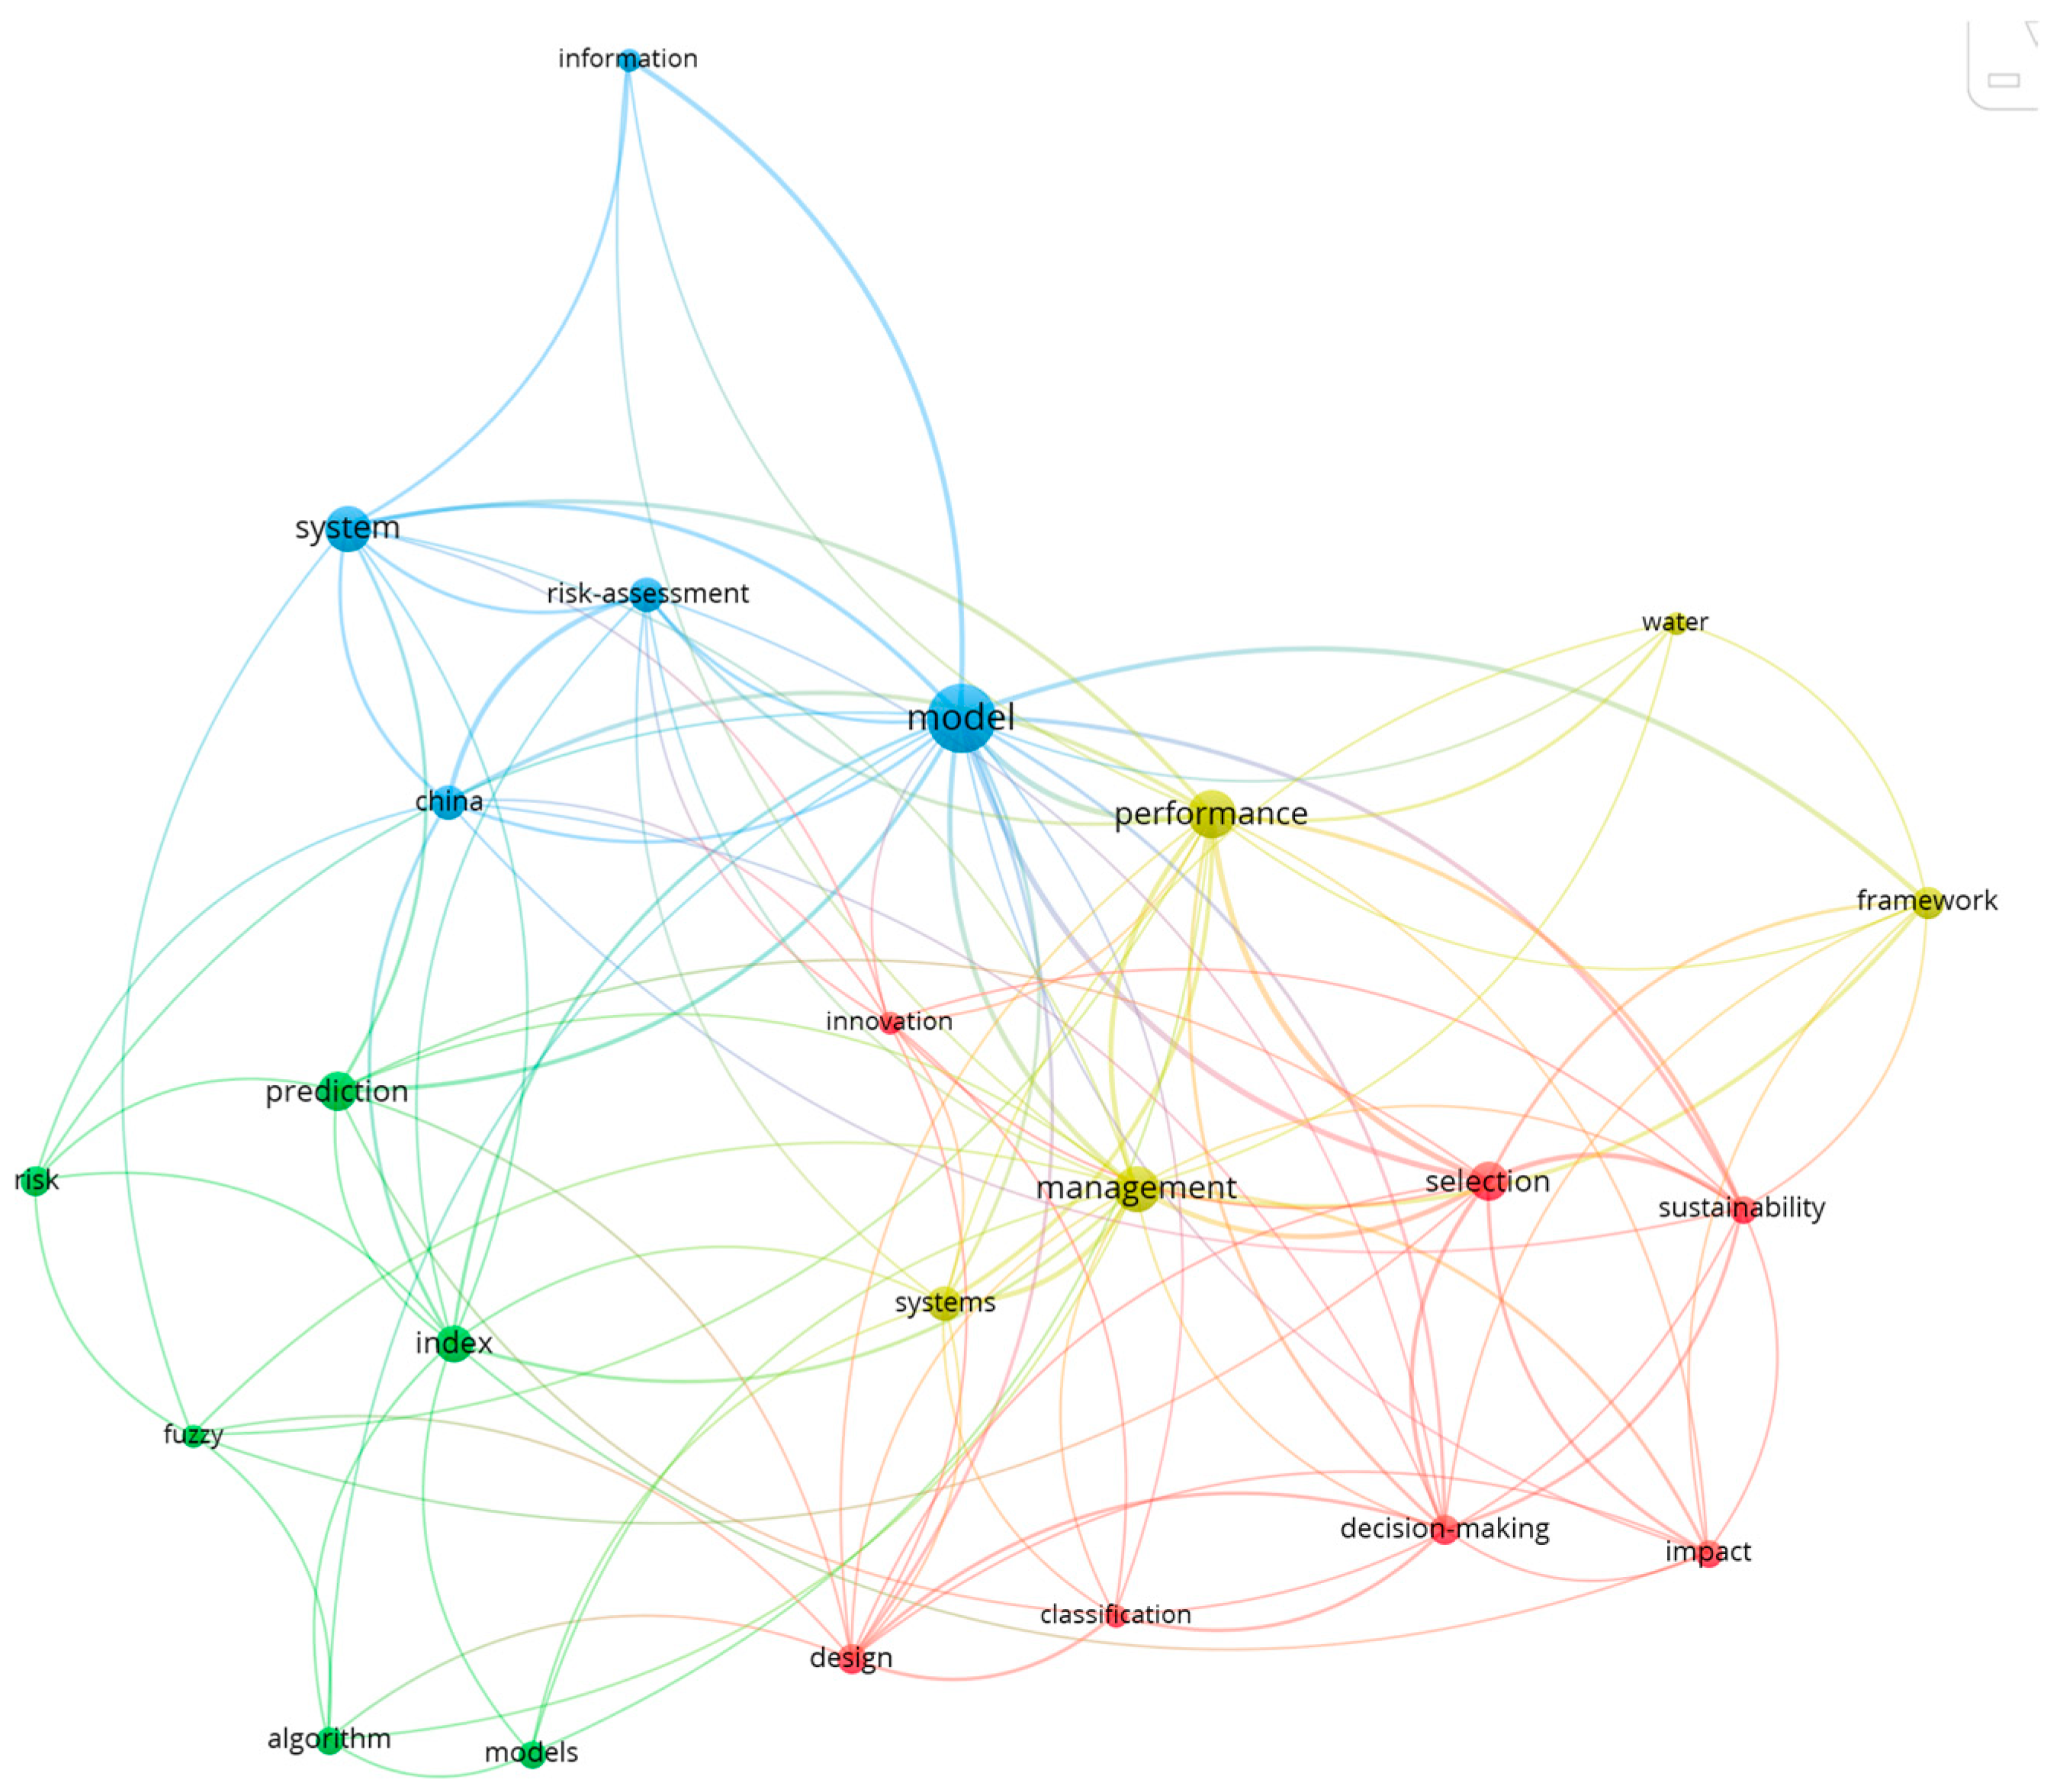
With the intention of cross-checking the results, a similar analysis was conducted in VOSviewer, in Figure 8. It is observed that most of the Keywords Plus listed in Figure 7 are also found in Figure 8, which proves the validity of the previous findings.
Four clusters are delimited, as follows:
  • First cluster (blue): information, system, risk-assessment, China, and model.
This cluster is oriented towards risk-assessment models, with a particular focus on China’s information systems.
  • Second cluster (green): prediction, risk, index, fuzzy, algorithm, and models.
The second cluster discusses prediction models, involving risk indexes, fuzzy methods, and advanced algorithms.
  • Third cluster (red): performance, management, systems, water, framework.
The third cluster is about efficiently managing the water resources, monitoring the systems, and improving the current frameworks for decision-making processes.
  • Fourth cluster (yellow): innovation, design, classification, selection, sustainability, decision-making, and impact.
The fourth cluster discusses identifying, classifying, and selecting the most efficient ideas and strategies that can improve the decision-making processes and contribute to sustainability.
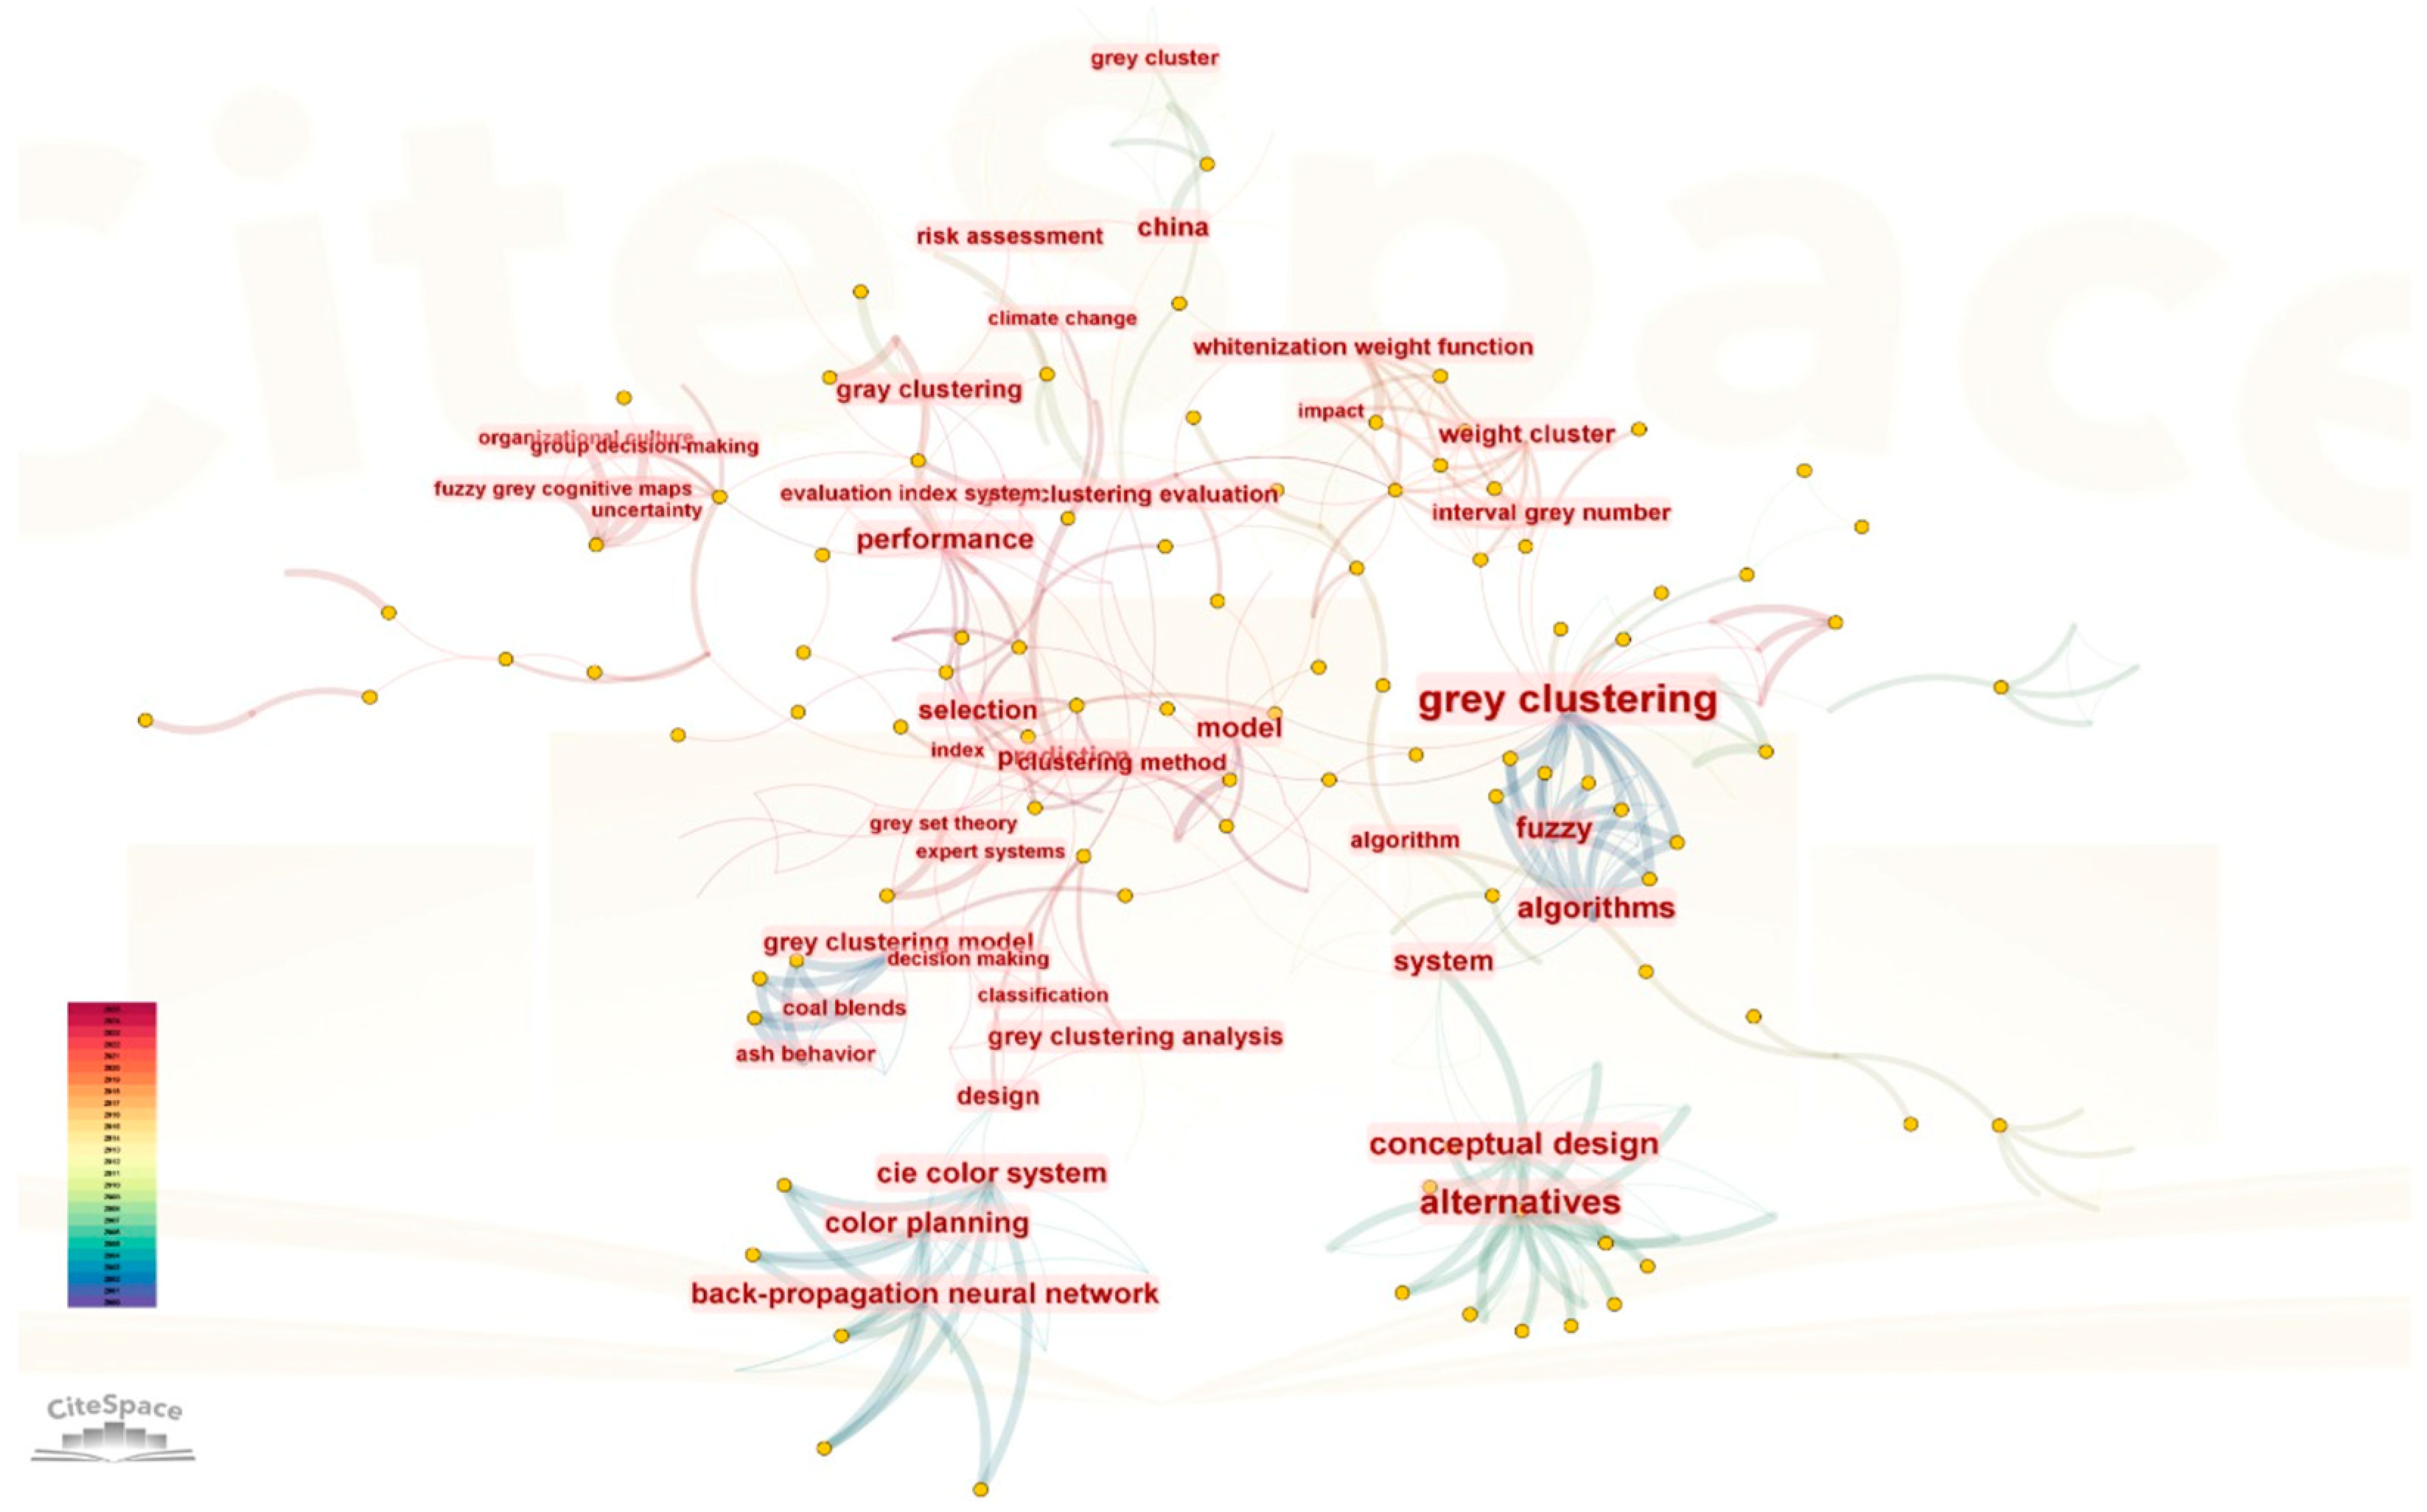
Going further with this topic, Figure 9 captures the same co-occurrence network for Keywords Plus but generated with CiteSpace’s assistance (the clusters in the below image cannot be easily depicted). In this figure, the extracted keywords are marked with dots, while the connection between keywords is reflated through a line.
By comparing the output from all three scientometric tools (Figure 7, Figure 8 and Figure 9), some common terms are noticed: model, China, system, risk assessment, design, etc.
Figure 10 represents a thematic map based on the authors’ keywords and was created considering the same strategy mentioned above. The following terms were eliminated since their number of occurrences is too high, and it is already known that the topics addressed in the dataset are about grey clustering: grey cluster, gray clustering, grey system, clustering analysis, grey clustering, clustering evaluation, model-based, clustering model, clustering approach, clustering method, grey systems, and cluster analysis.
The below picture is delimited into four distinct sections: niche themes (specialised, focused)—left corner; motor themes (main, powerful)—right corner; basic themes (common, essential)—bottom right corner; and emerging or declining themes (growing, new or losing popularity, fading)—bottom left corner.
The niche themes include mainly combinations of words associated with methods, techniques of evaluation, and performant algorithms utilised in the selected manuscripts (e.g., generic algorithm, grey model, fuzzy comprehensive evaluation, analytic hierarchy process, factor analysis, etc.). Apart from this, the presence of some terms uncovers the areas in which those methods are applied and have a considerable contribution, such as risk prediction, safety management, environmental quality (e.g., water), and sustainability.
The motor themes underline domains in which grey system theory is applied. As can be observed, the areas are wide and diverse: airplane boarding in the COVID-19 pandemic context, environmental vulnerabilities, remote sensing, evaluation, and higher education. All are topics of high relevance in today’s world, proving that grey clustering and artificial intelligence algorithms can easily investigate uncertain and complex data and offer smarter decisions and efficient strategies.
Basic themes contain mostly terms related to methods and types of analyses (e.g., grey relational analysis, grey clustering analysis, grey incidence analysis, evaluation index system, grey cluster model, interval grey number, entropy-weight method, etc.), which are combined and applied in many research papers related to risk assessment, environment (air quality), sustainability, security, and multi-dimensional data (spatiotemporal characteristics).
Lastly, emerging or declining themes uncover, apart from the usual types of investigations discussed in the previous categories (e.g., whitening weight function, grey relational analysis, grey discriminant analysis, grey cluster analysis, artificial intelligence, consensus model, grey system theory), a new field in which they are applied: wind farm. In regard to the appearance of the foundational research directions in this area of emerging or declining themes—such as whitening weight functions, grey relational and discriminant analyses, general grey cluster models, consensus models, and grey system theory itself—it can be added that these concepts are being adapted on a regular basis to new computational environments (e.g., large-scale datasets, AI-assisted modelling, hybrid uncertainty frameworks), thus making them appear in the emerging themes quadrant as evolving themes rather than stable or basic themes. Second, the appearance of the “wind farm” research theme as a newly emerging application domain can be put into connection with the recent expansion of grey clustering into renewable energy analytics. This development is driven by the inherently uncertain, nonlinear, and variable nature of wind energy systems, which makes the use of the grey-based approaches fit perfectly with the problems associated with this research field. Among applications, one can consider the classification of turbine performance, predicting energy output under incomplete information, and supporting investment or maintenance decisions. Compared to more established environmental clusters (e.g., water or air quality), wind energy applications remain underexplored, marking a clear research gap and a promising direction for future inquiries.
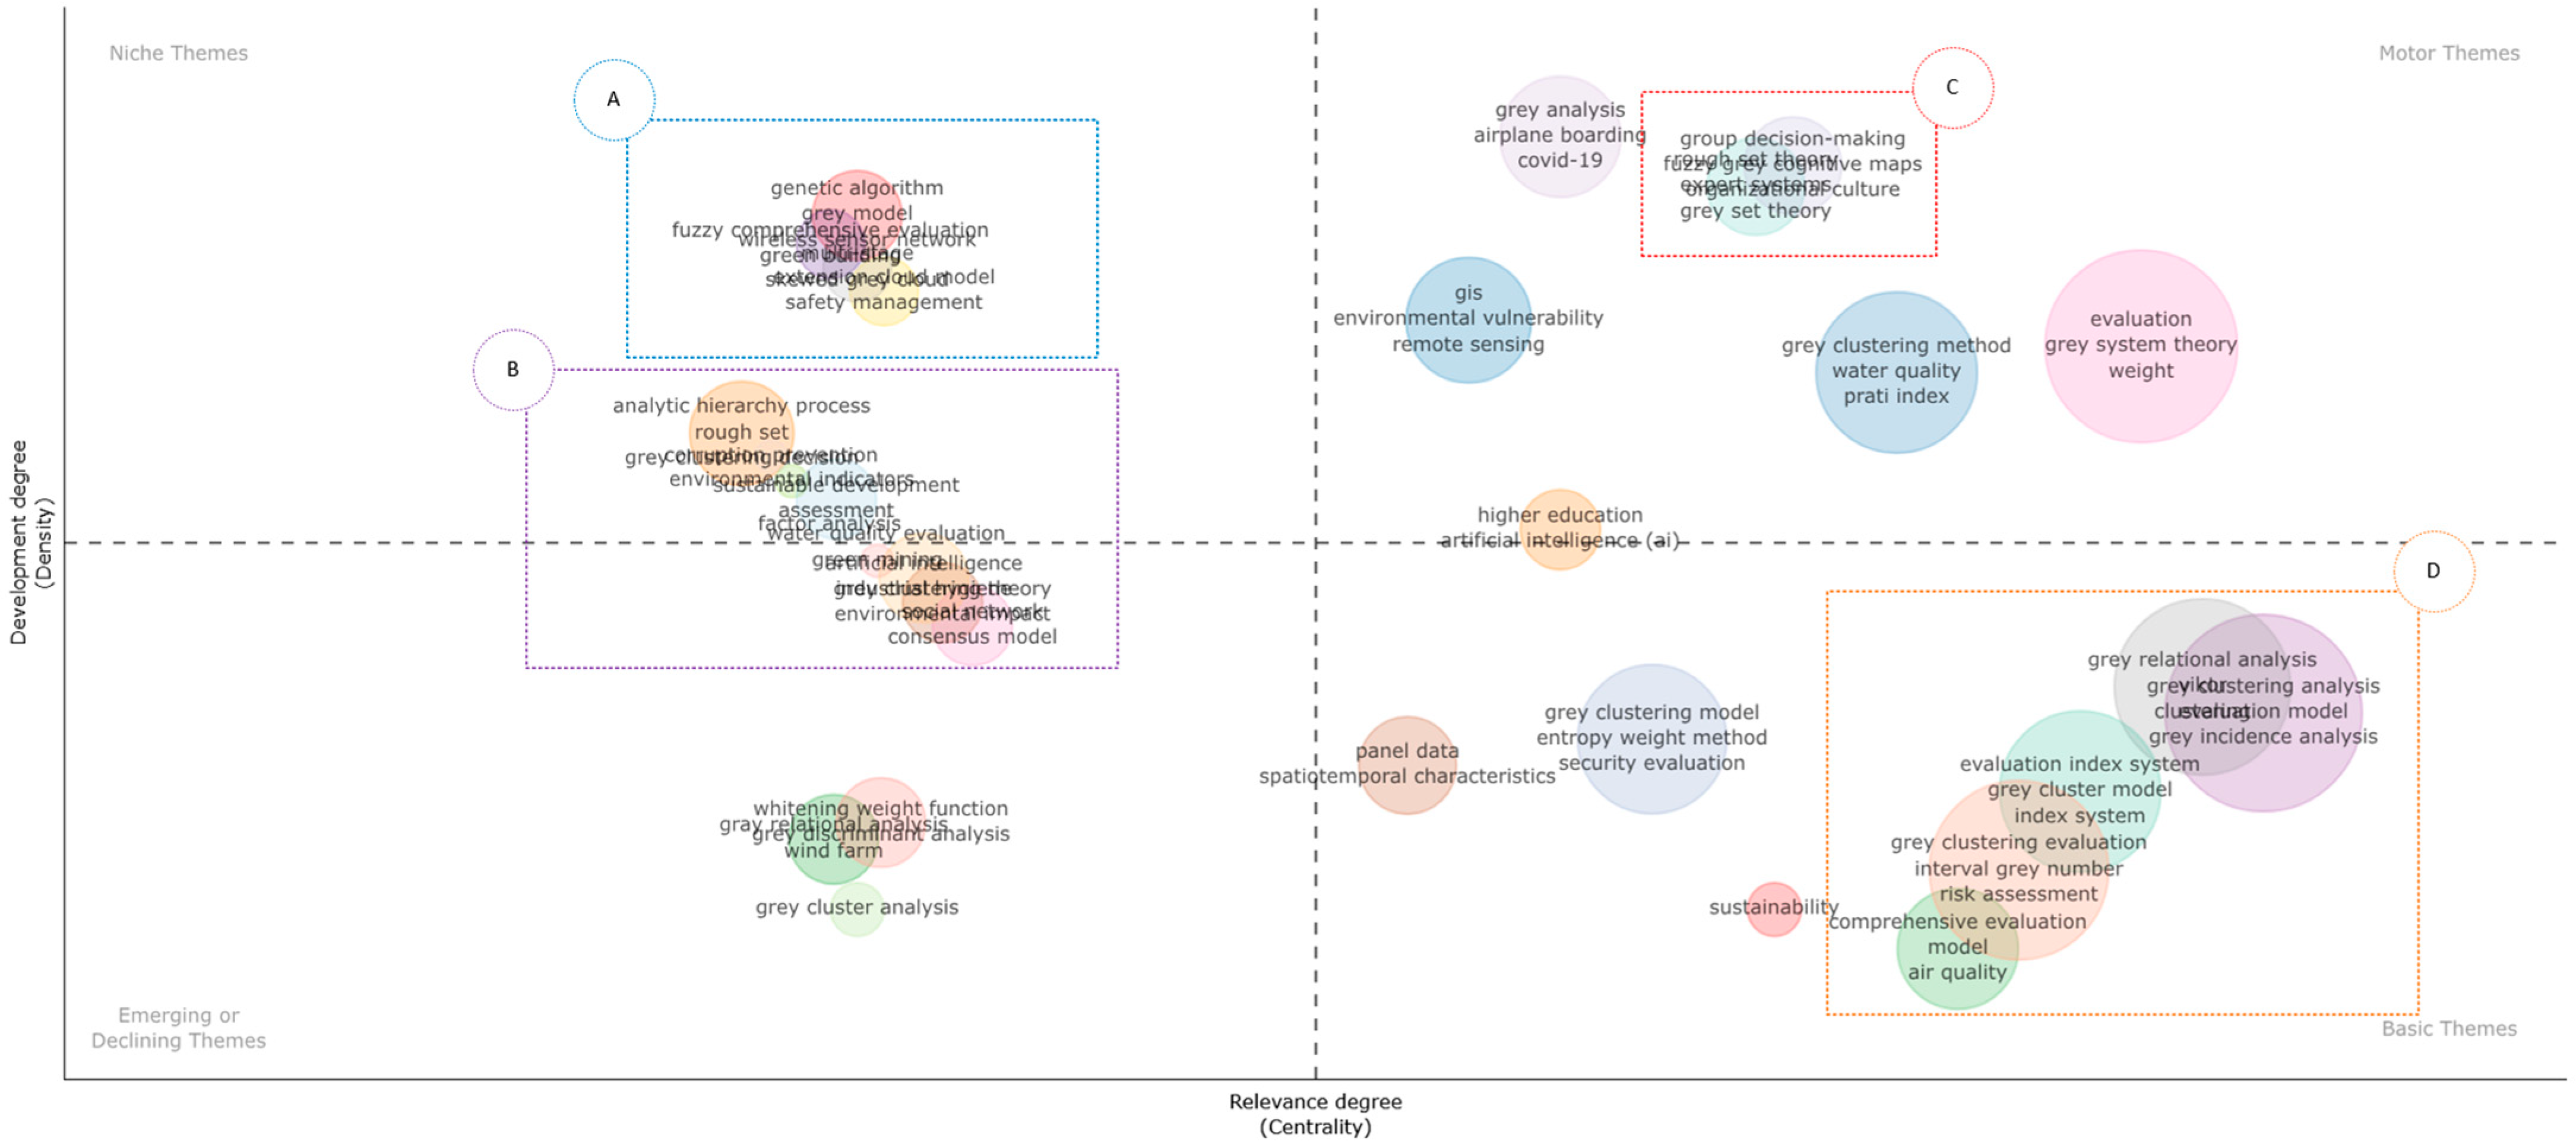
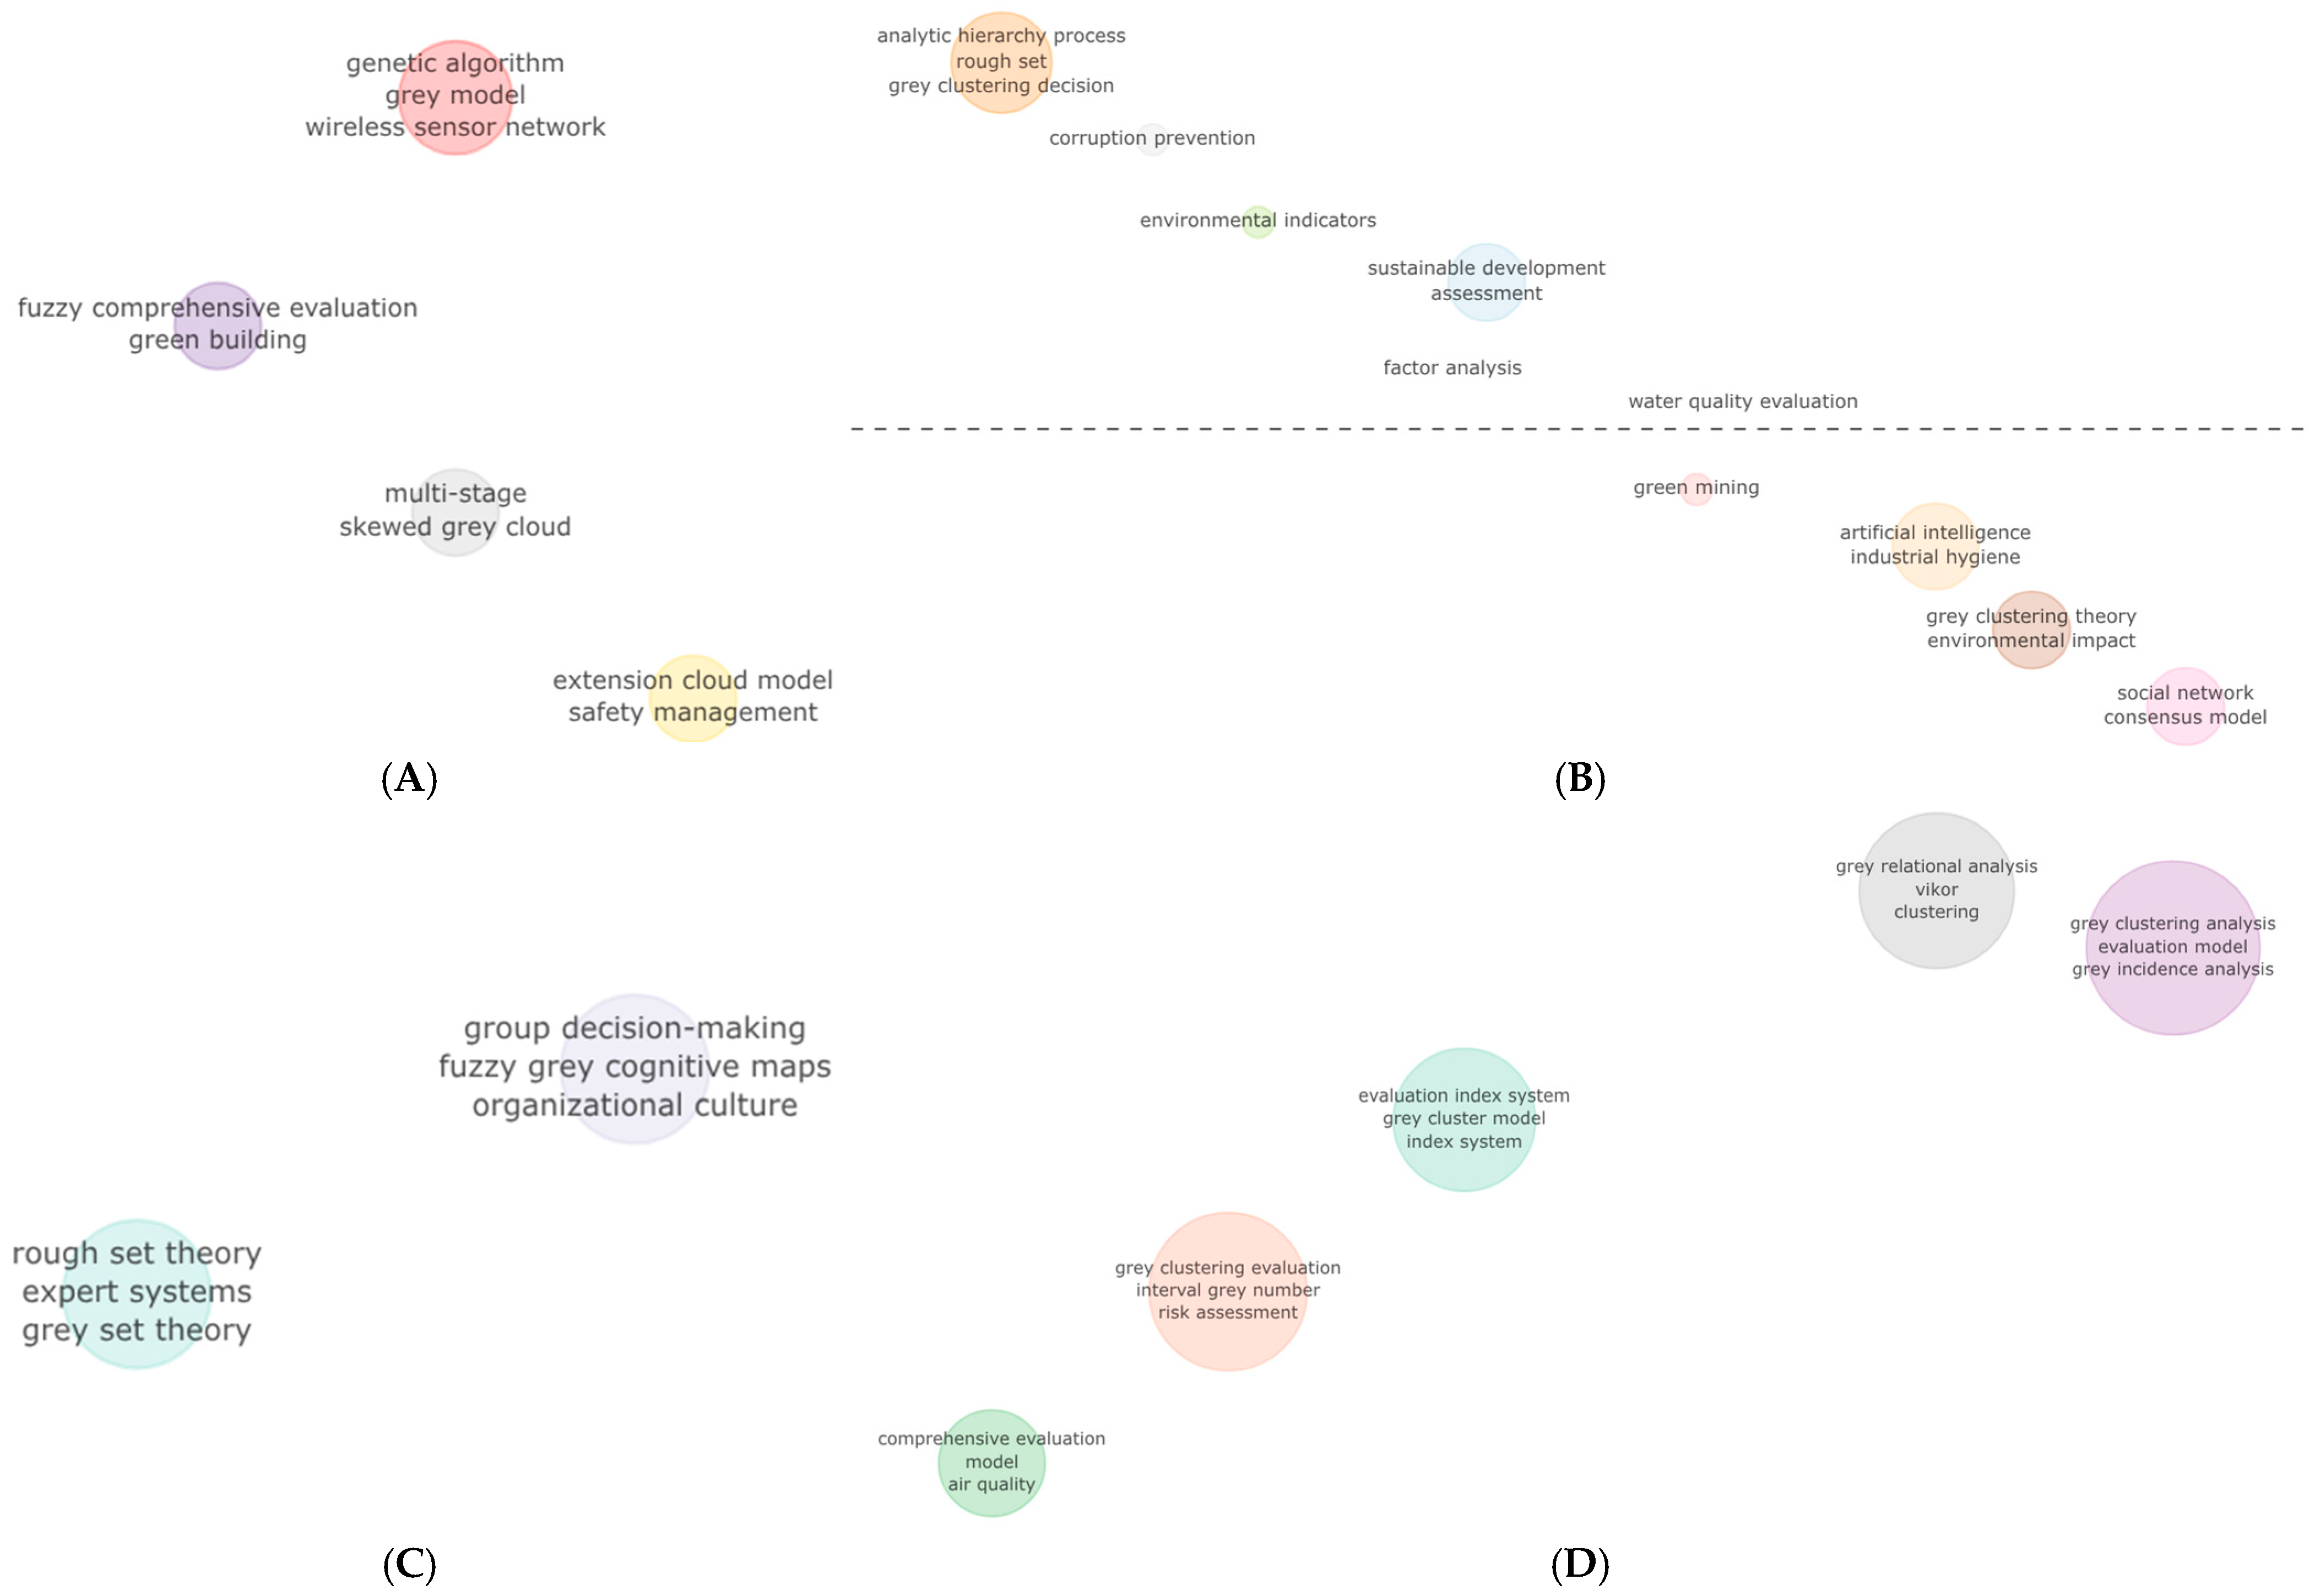
Figure 11 continues the investigation performed for Figure 10, but this time, it is focused on the expansion upon overlapping zones A, B, C, and D.
Zone A is placed inside the niche themes quadrant, proving that areas such as the application of grey model and generic algorithms in wireless sensor networks, fuzzy comprehensive evaluation in the green building field, combined multi-stage and skewed grey cloud, and extension cloud model in safety management, are addressed by small groups of researchers, are highly specialised topics, and have a limited impact.
Zone B is placed at the intersection between niche themes and emerging or declining themes. This suggests that the mentioned topics are in transition, being highly specialised and starting to gain attention, visibility, or even losing their relevance in the academic literature. Some examples of topics that are placed in the niche themes sector refer to sustainability, corruption prevention, water quality investigated by using the analytic hierarchy process, grey clustering decision, and factor analysis. Topics such as green mining, industrial hygiene, environmental impact, social network with techniques based on artificial intelligence, and grey clustering theory are found among the emerging or declining themes.
Zone C is placed inside motor themes and uncovers the central topics within the domain under investigation. It combines decision-making, tools for handling uncertain or complex data, and organisational factors to combat current challenges, problems in any sector, and enhance the strategies.
In the end, zone D is placed in the basic themes quadrant and represents the common subjects and techniques in the field. The main areas of interest are air quality, risk assessment, and the investigation conducted in the papers involves grey clustering analysis, evaluation model, grey incidence analysis, grey relational analysis, VIKOR, interval grey number, and comprehensive evaluation model.
Moving beyond the descriptive presentation of clusters, the thematic networks generated by the specific software present a series of relationships that shape the intellectual structure of grey clustering research. For instance, environmental evaluation clusters (air quality, water quality, urban ecological security) share methodological dependencies with the risk assessment clusters, where grey clustering is commonly hybridised with AHP, entropy weighting, or fuzzy–grey models. This cross-link indicates that methodological choices in risk-oriented studies frequently influence environmental research design, yet the reverse influence—environmental-domain insights informing methodological refinement—is comparatively underdeveloped.
In a similar manner, the sustainability and industrial engineering clusters overlap with clusters related to performance evaluation and multi-criteria decision-making. This situation suggests that grey clustering has become a unifying mechanism for structuring complex problems across domains, though the transferability of cluster structures (e.g., cluster boundaries, whitening functions) remains insufficiently explored. On the other hand, methodological clusters (e.g., grey relational analysis, entropy methods, grey cloud) act as central points. These clusters are linking incongruent application domains, as observed in the analysis. Also, the thematic maps reveal that these methods evolve faster than their theoretical grounding, creating a gap between methodological innovation and theoretical consolidation.
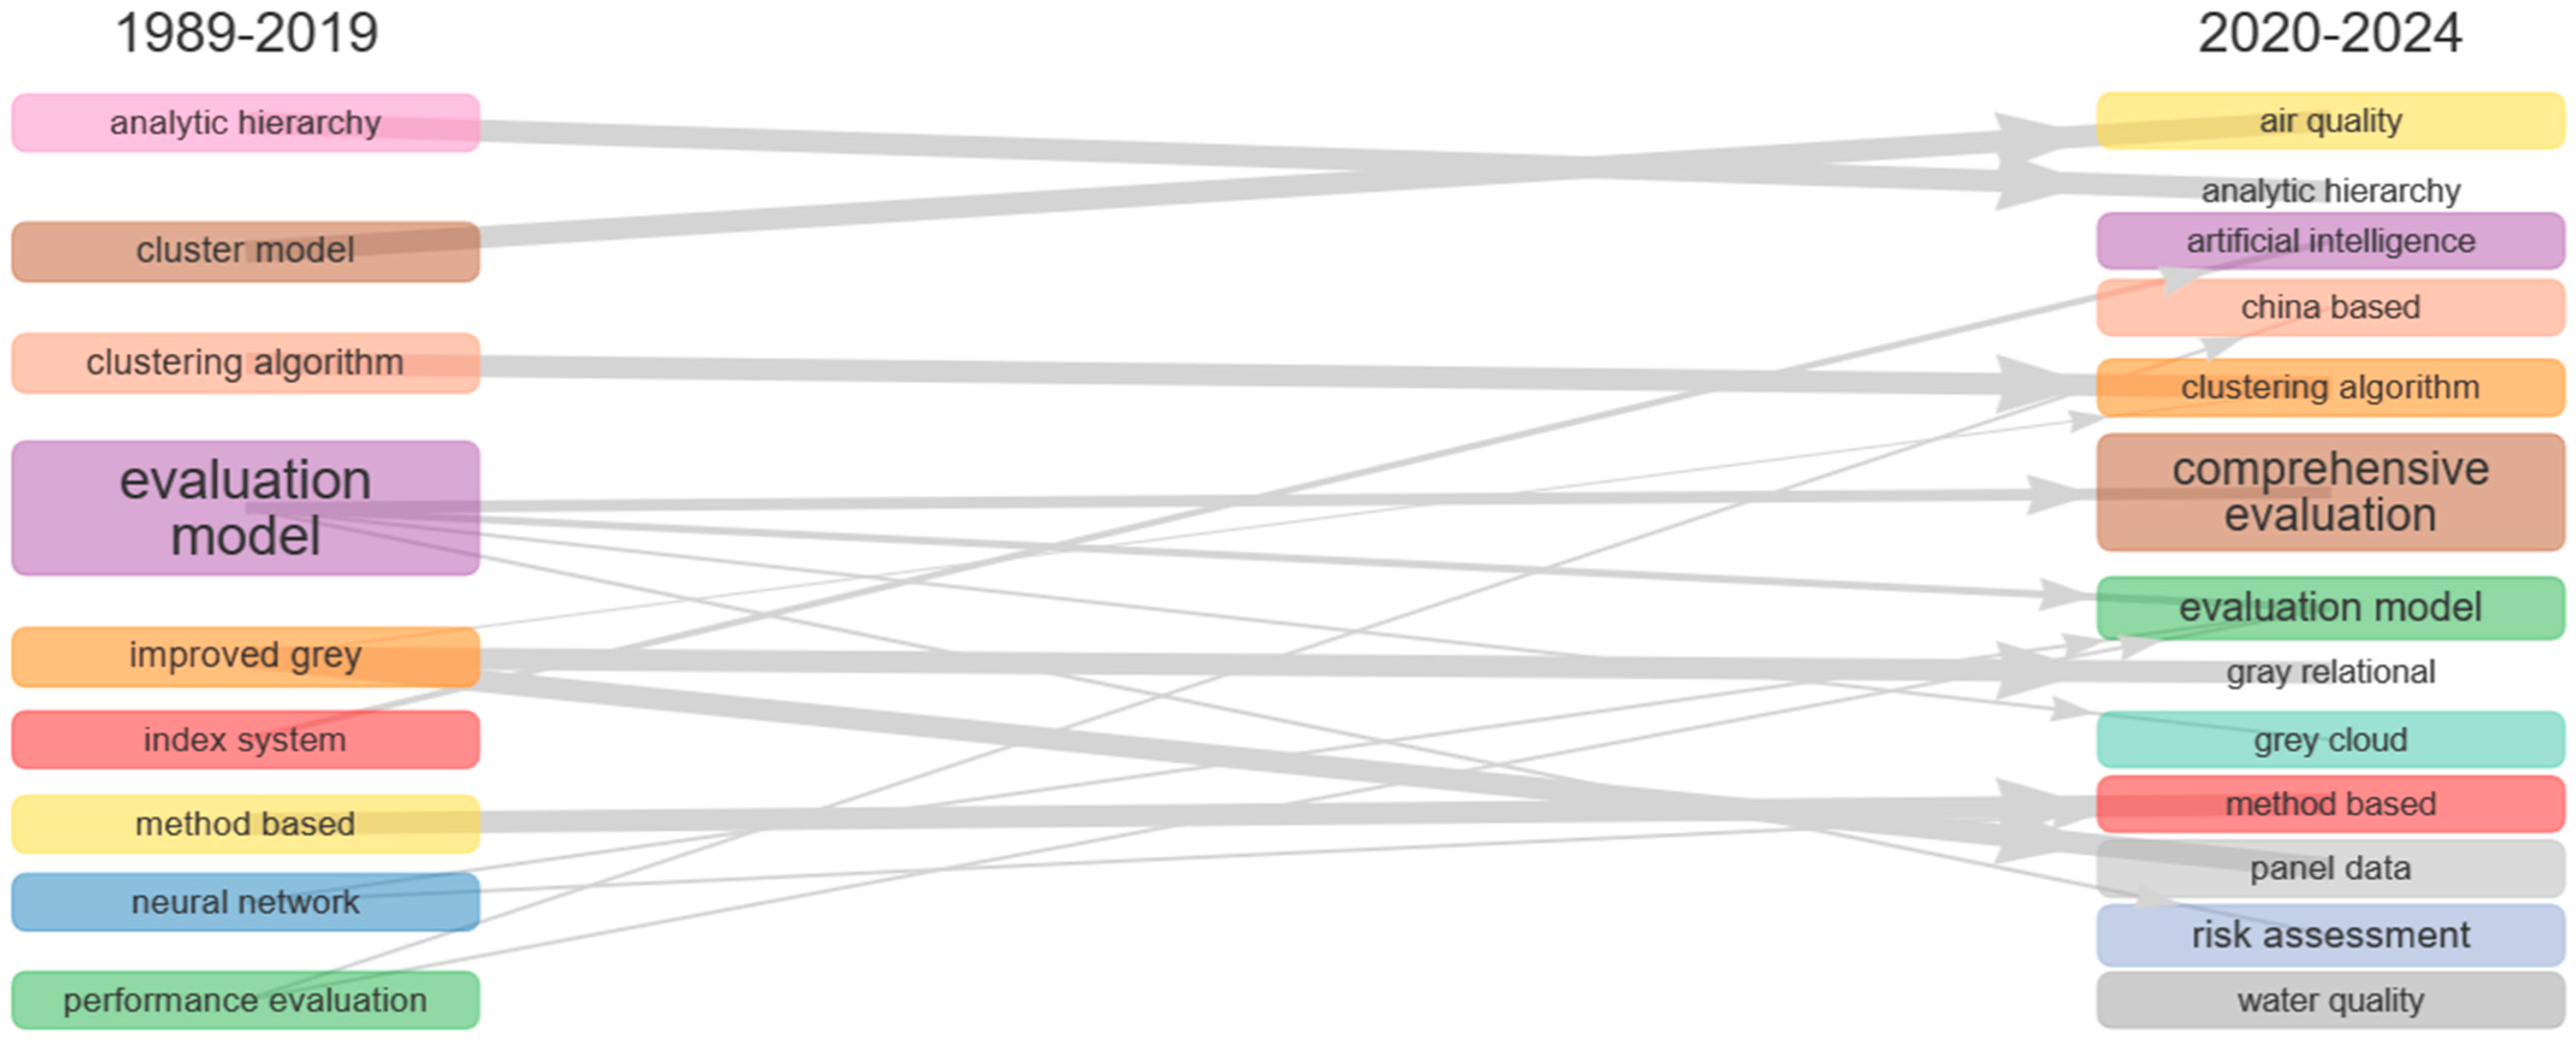
Figure 12 captures the thematic map evolution on bigrams in titles. The visual representation is composed of two time intervals: one is dedicated to the period between 1989 and 2019, while the second one covers the period between 2020 and 2024. It is noticed that bigrams such as “analytic hierarchy”, “clustering algorithms”, “evaluation model”, and “method-based” are found in both intervals, proving their power and performance in analyses, classifications, and assessments in any domain.
In the second time frame, a significant interest is observed in topics such as air and water quality, risk assessment, with a particular attention to large countries, such as China. Apart from these, new types of investigations are depicted due to technological advancements, such as artificial intelligence, grey relational, and grey cloud.
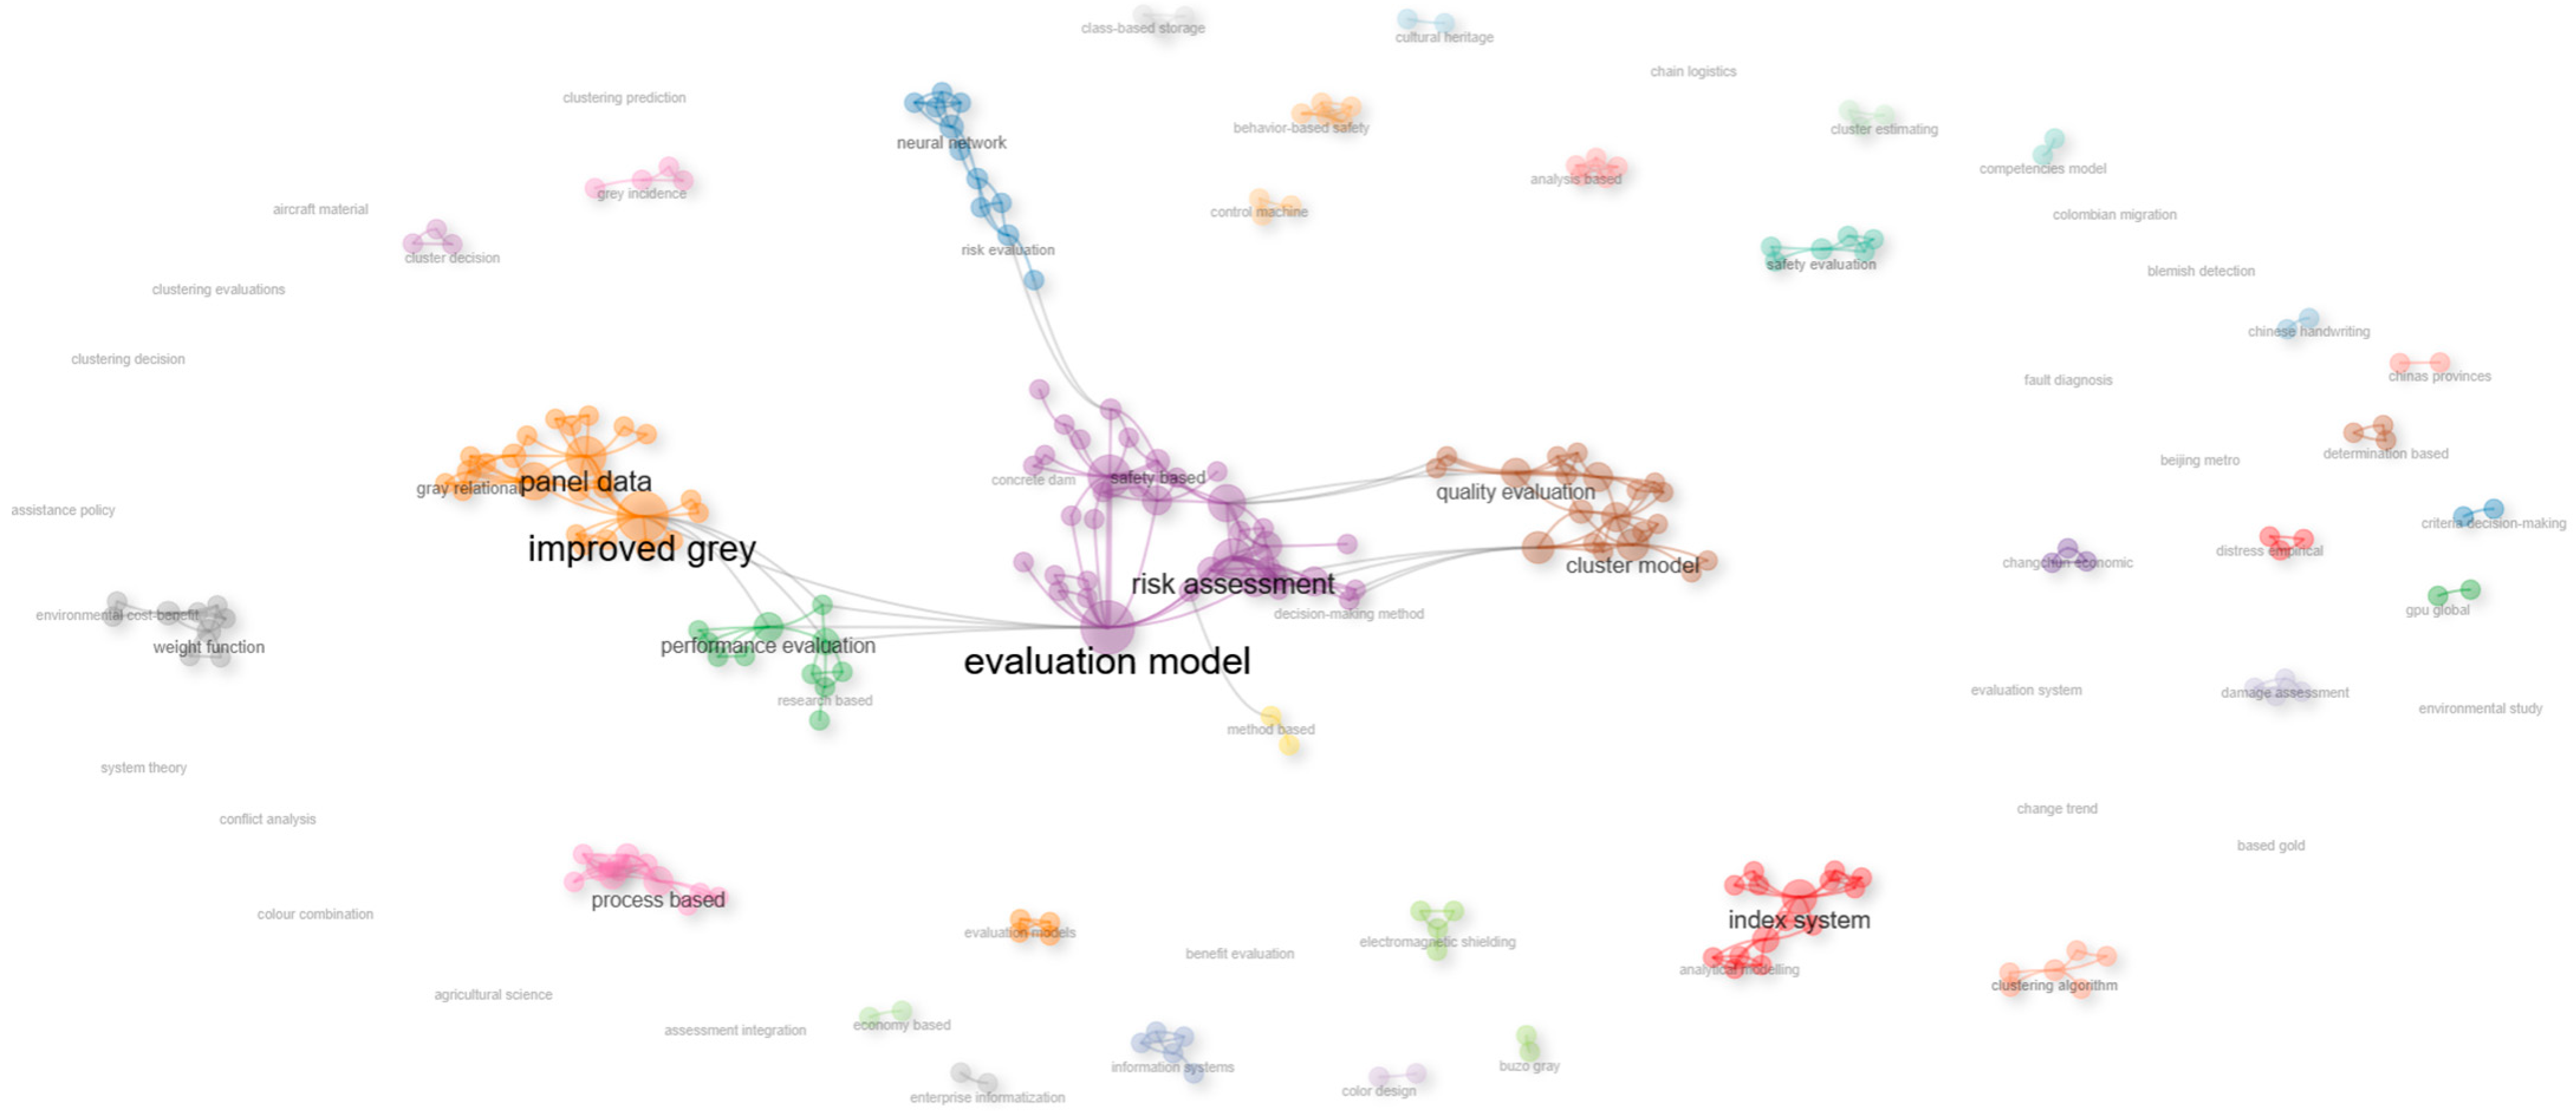
Figure 13 represents the thematic map evolution on bigrams in titles, for the first period: 1989–2019. In terms of main techniques and types of analysis, the following are noticed: clustering prediction, grey incidence, clustering evaluations, neural network, method-based, index system, analytical modelling, clustering algorithm, and decision-making method.
The key areas of focus are related to safety evaluation, damage assessment, environment, economy, agriculture, conflicts, assistance policy, chain logistics, aircraft materials, enterprise informatisation, electromagnetic shielding, and cultural heritage. The domains are diverse and cover a wide variety of subjects, which proves once again the power of grey theory and artificial intelligence in analysing complex and uncertain information, and reinforces their high contribution in evaluating performance, and enhancing the strategies by guiding decision-making processes.
Furthermore, the presence of words such as “Beijing” and “Chinese” suggests the high research interest in large countries and very populated urban environments.
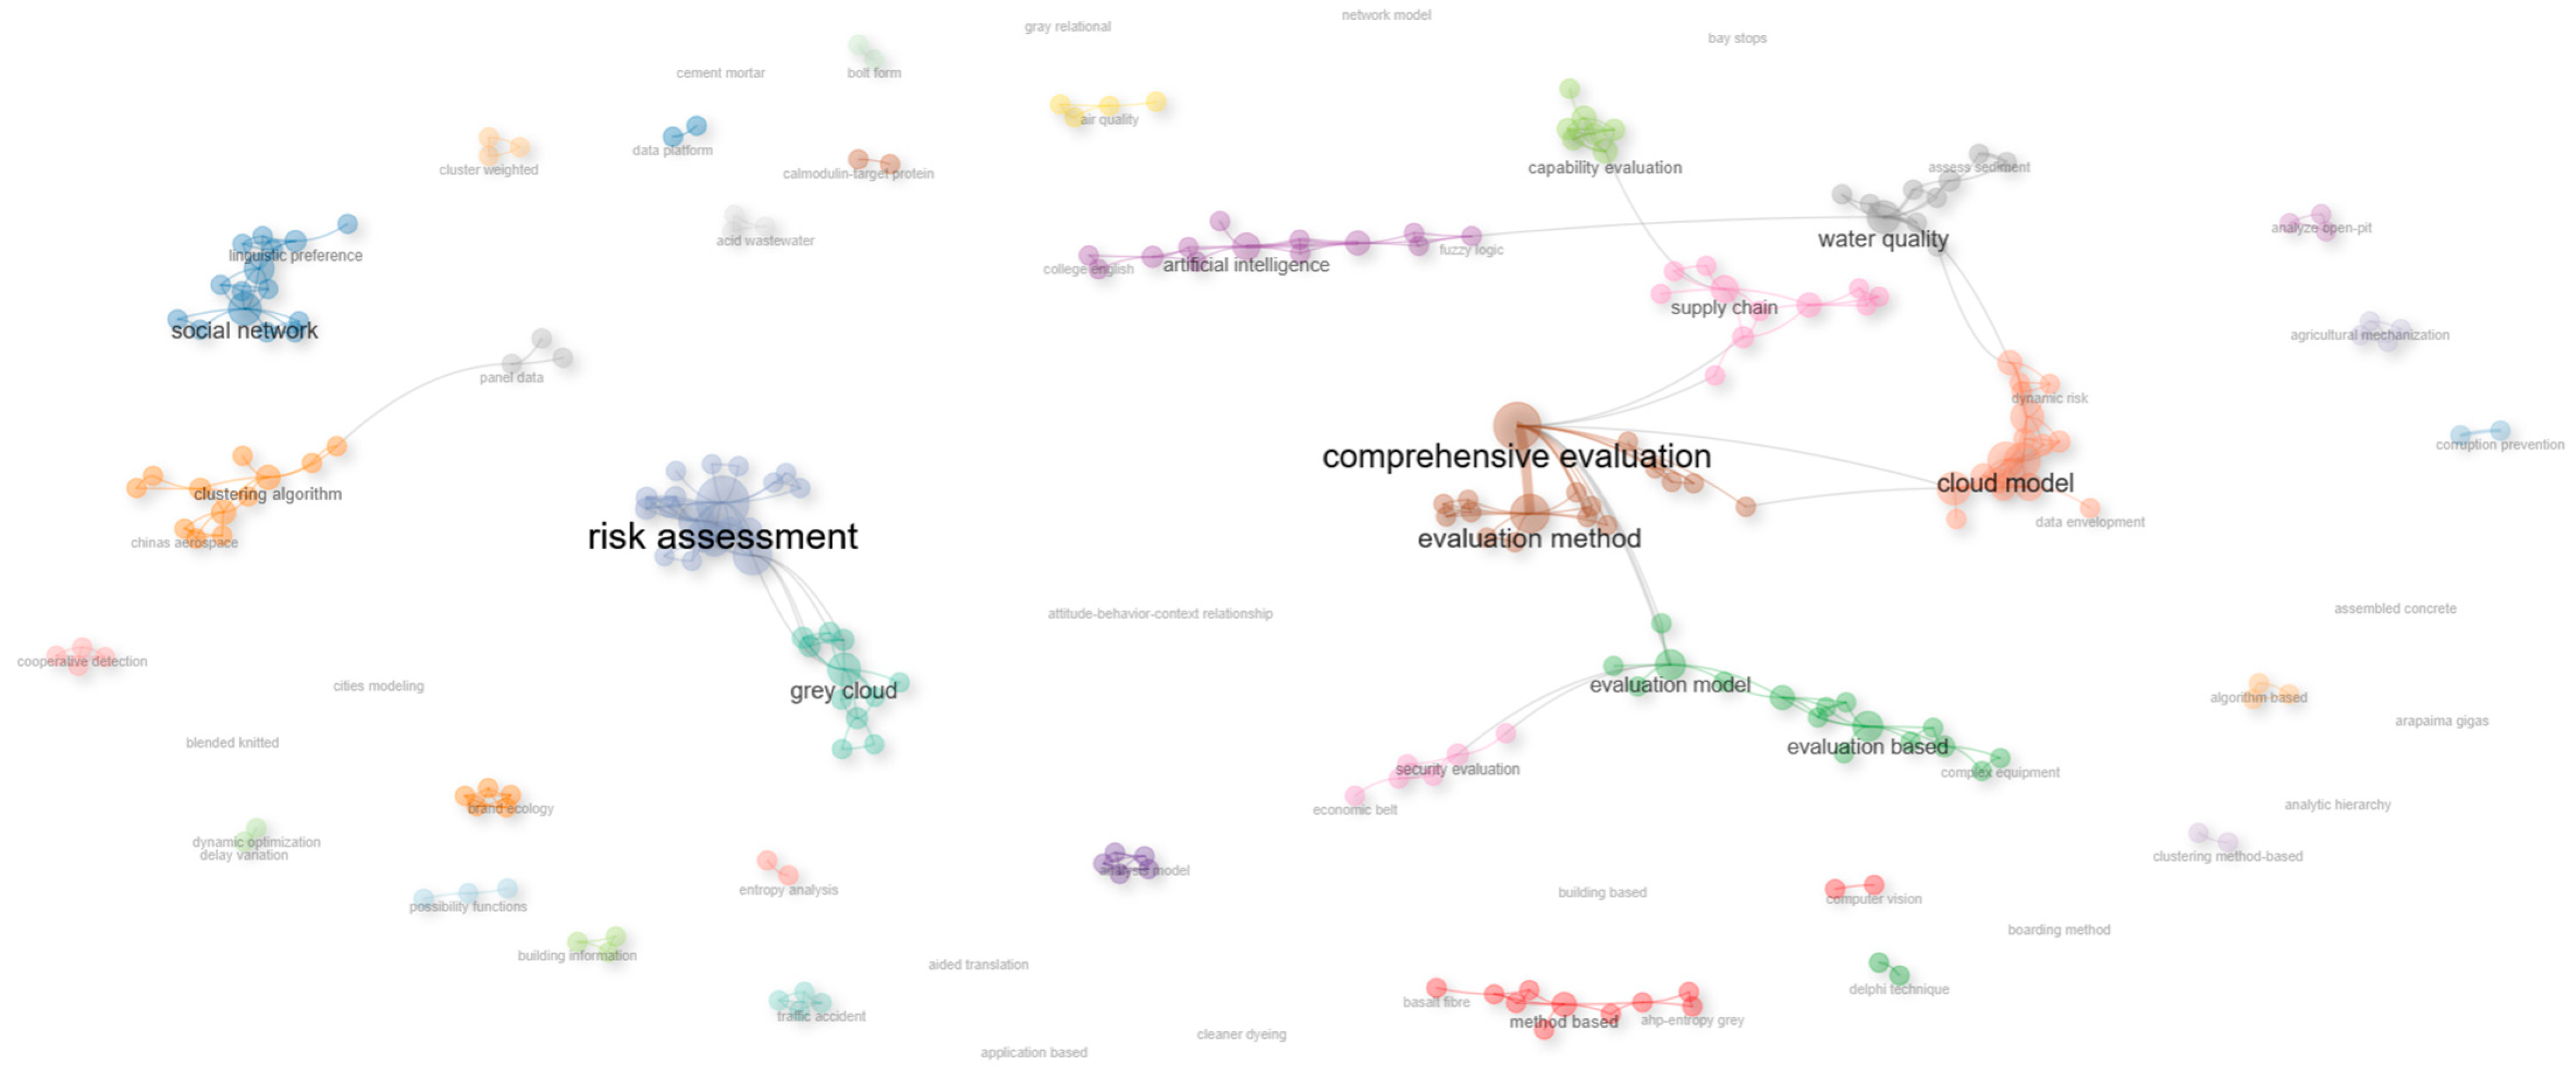
In the same manner, Figure 14 was created, including the thematic map evolution on bigrams in titles, for the period between 2020 and 2024.
By investigating the clusters delimited in the below visual representation, some new techniques and analyses can be noticed, due to the technological advancements and grey theory evolution: cooperative detection, dynamic optimisation, possibility functions, entropy analysis, grey cloud, fuzzy logic, cluster weighted, and AHP-entropy grey. This highlights that the methods’ performance is constantly improving and the results are increasingly more accurate.
Furthermore, new domains of grey systems’ application are also visible, such as ecology, traffic accidents, cleaner dyeing, corruption prevention, water and air quality, cement mortar, and acid wastewater. The themes of research are continuously adapting to the evolving realities and the modern world’s challenges and needs.
Going beyond the keywords extracted when the thematic maps have been created and analysing the papers comprised in each of the clusters in the thematic maps, a series of research gaps can be identified, as discussed in the following.
For the clusters featuring elements from environmental and ecological areas, a lack of generalizability and comparisons between various climatic contexts has been observed, as most of the works in this field refer to China. Also, it has been noticed that there is a limited integration of remote sensing, IoT, and high-frequency data streams, despite their relevance to environmental uncertainty.
Furthermore, for the clusters discussing issues related to risk and safety, it can be observed that most of the models are static, with few models on the dynamic or time-evolving grey clustering models for hazard detection. Even more, only a few papers are exploring the risk propagation or are conducting analyses involving multi-agent or multi-layer systems.
In the area of sustainability, urban development or regional science, a reduced use of frameworks that combine socio-economic, environmental, and infrastructural indicators has been noted, with even fewer studies focusing on investigating transferability issues across cities, regions, or development stages.
In the case of the clusters in the emerging area, especially the studies related to wind farms, it has been observed that there is a limited theoretical grounding for grey-based approaches to stochastic renewable energy systems.
Lastly, in the case of the methodological clusters, it can be underlined the fact that there is a lack of methodological foundation on how the values for the possibilistic or whitenisation weight functions are built; thus, there is still a need for more research on this area in order to build a unified evaluation standard for such functions.
Thus, for future theoretical development, more attention can be given to the creation of the whitenisation or possibilistic weight functions, on the establishment of the importance weights, or on supporting high-dimensional, temporal, and multi-source data, which would ensure the competitiveness of the grey clustering approaches in the complex and adaptive environments. Nevertheless, the integration with artificial intelligence might be an exploration area in which a formal mathematical framework could be useful in explaining how grey uncertainty interacts with learned feature representations. Even more, the integration of grey clustering methods into agent-based models could enlarge the applicability areas of this method, making it possible to be applied to complex and dynamic simulation environments.

4.4. Topics Discovery Through LDA and BERTopic

This section is focused on two popular techniques, namely LDA and BERTopic. Used together, their purpose is to contribute to a better understanding of the leading themes and, at the same time, offer a global overview of the under-investigated domain. The rationale behind the involvement of both methods is based on the fact that they complement each other.
LDA is a topic-modelling broadly used for identifying general areas of interest, as it offers results which are stable and easy to interpret [49,50,51]. On the other hand, BERTopic uncovers more specific themes, as it involves advanced language models which can better capture the semantic meanings, especially when diverse terminology is used. By combining the outcome of both methods, a stronger comprehension of the research conducted in the scientific literature about grey clustering methods and applications is ensured.
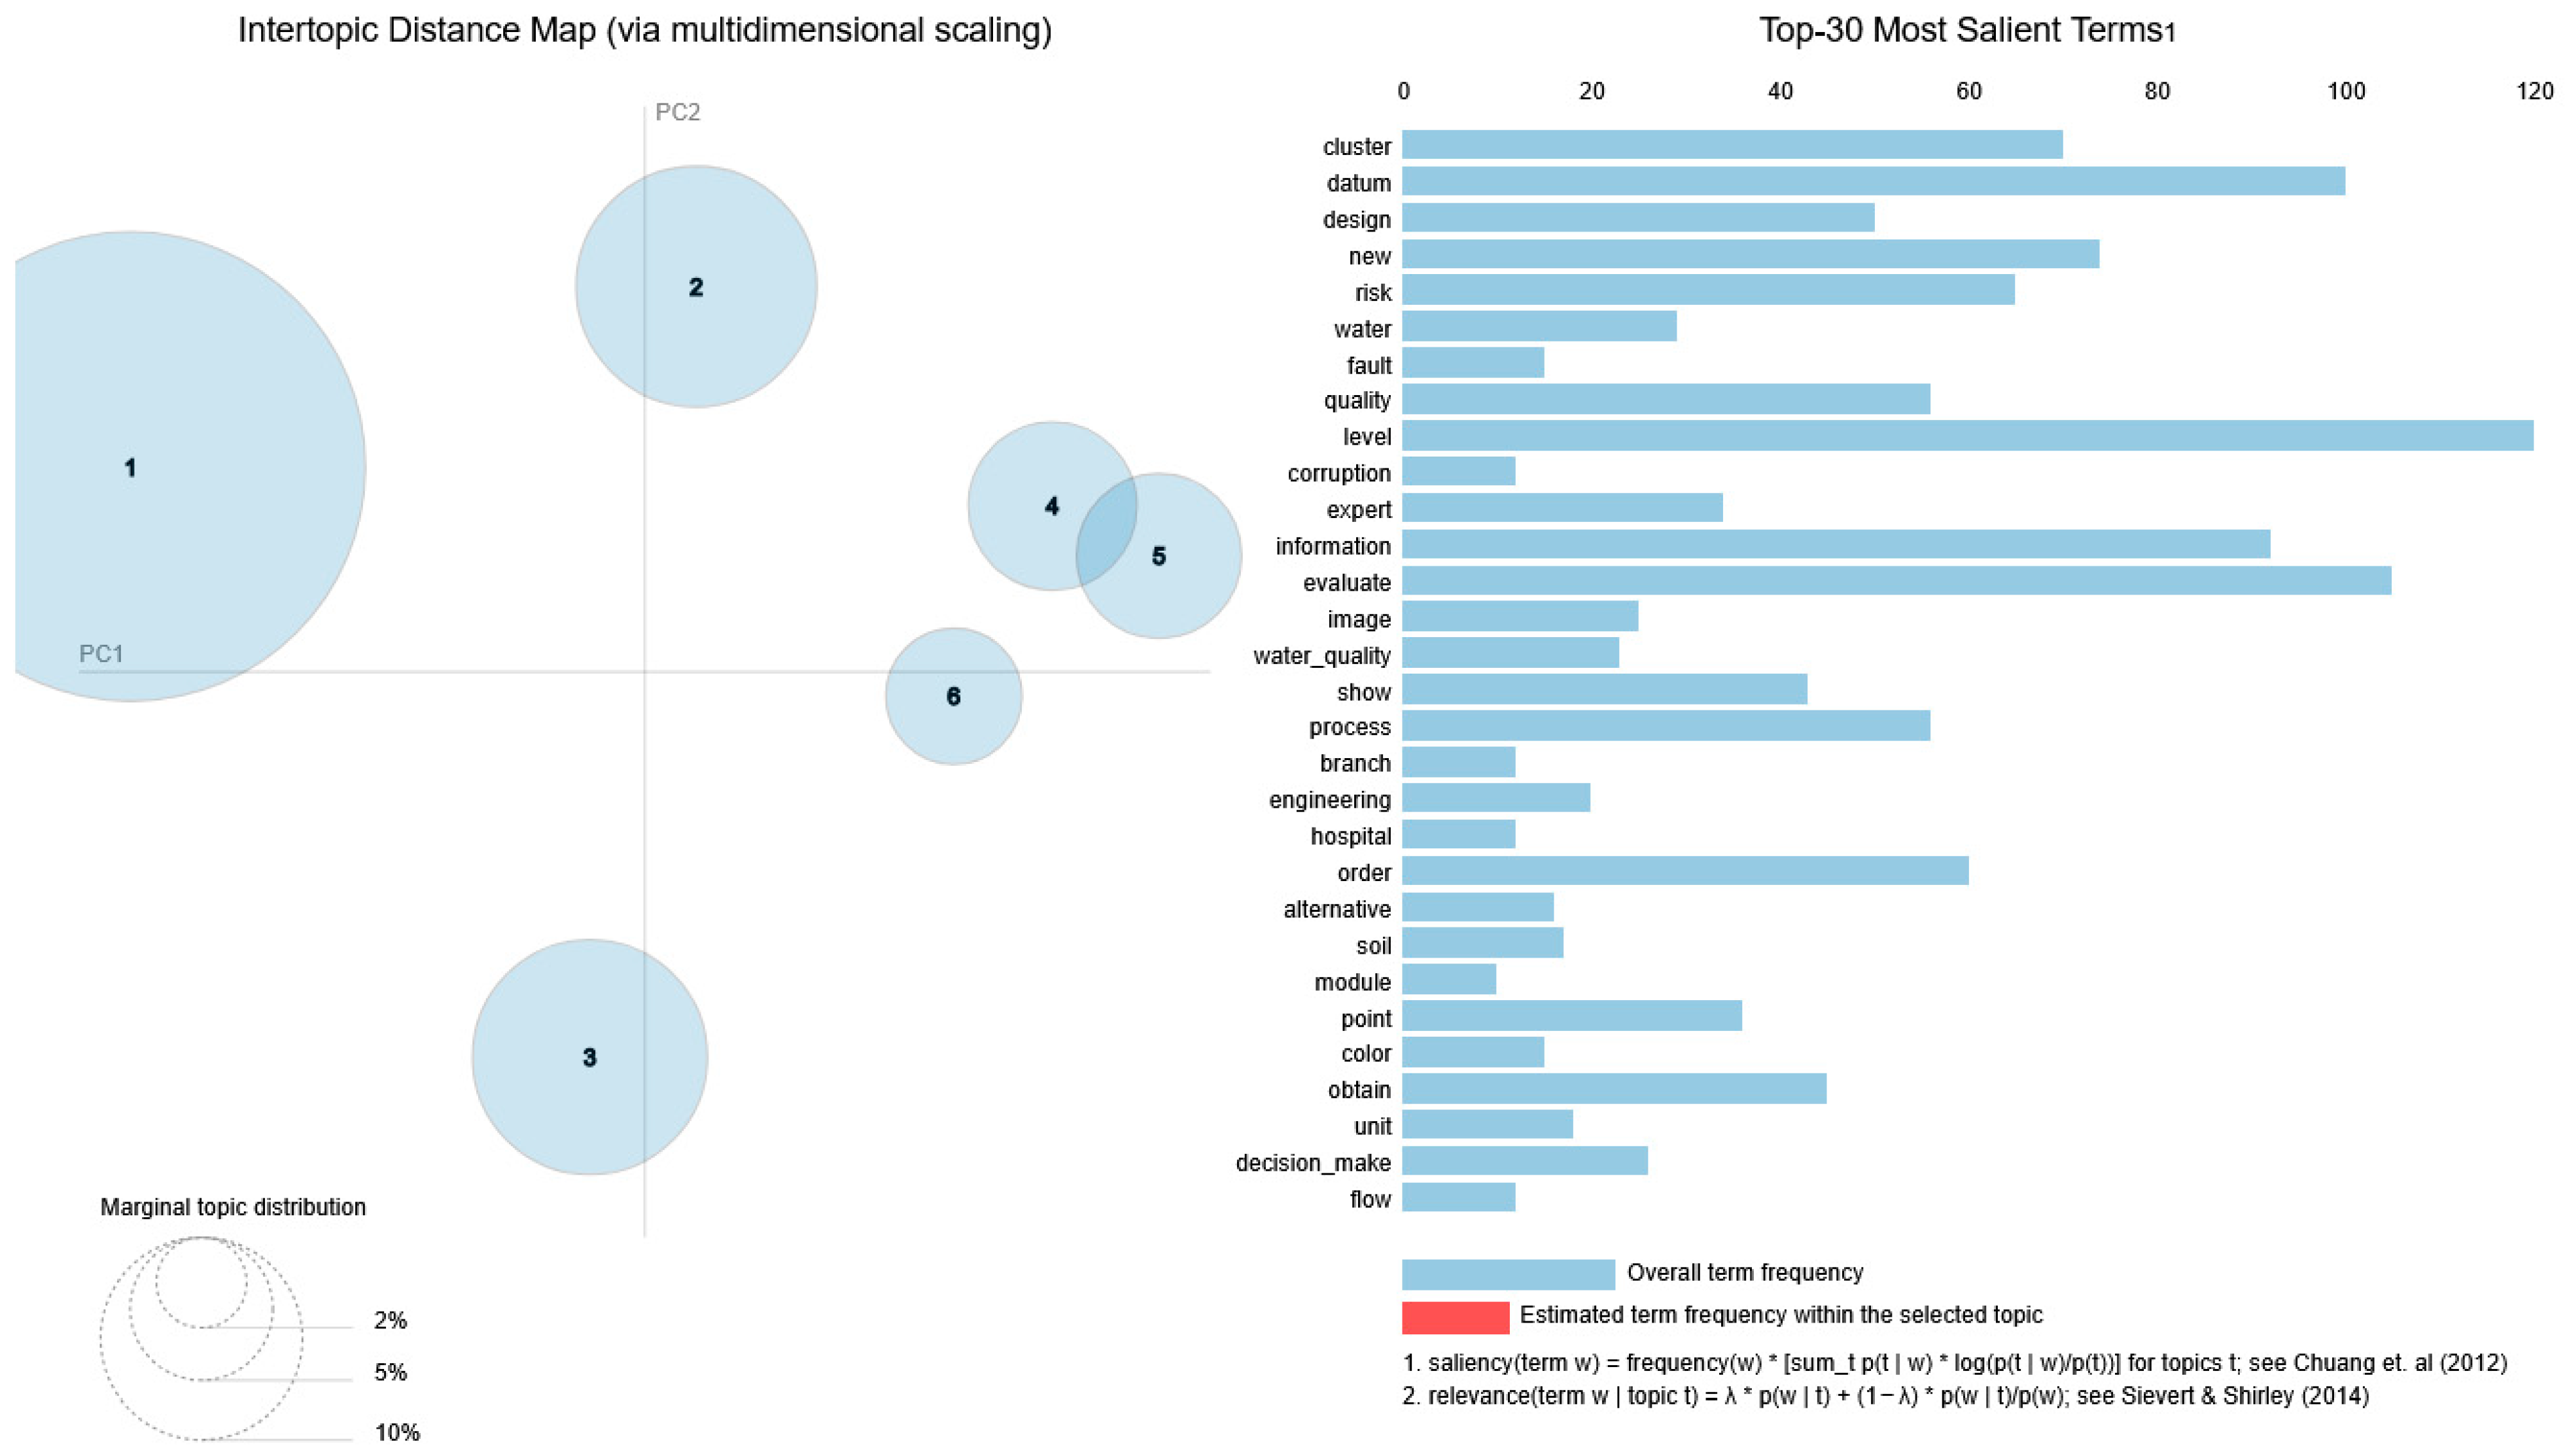
An LDA analysis was first conducted on the papers’ abstracts in order to identify the research topics and the relationships between them. As a result of the LDA analysis, six main topics have been determined, as depicted in Figure 15.
Before investigating each figure, a brief interpretation of the LDA intertopic distance maps will be useful for readers who are not familiar with this type of analysis. All the below images include several circles which represent the topics uncovered by the LDA model, and the distance between them suggests their degree of similarity or difference (closer circles include related topics which share similar vocabulary, while far-apart circles incorporate distinct topics and specialised themes). The size of the circles hides the importance of the topic in the field: the larger the size, the higher the topic’s significance. This interpretation assists interested readers in understanding how topics addressed in the field are distributed and connected in the scientific literature.
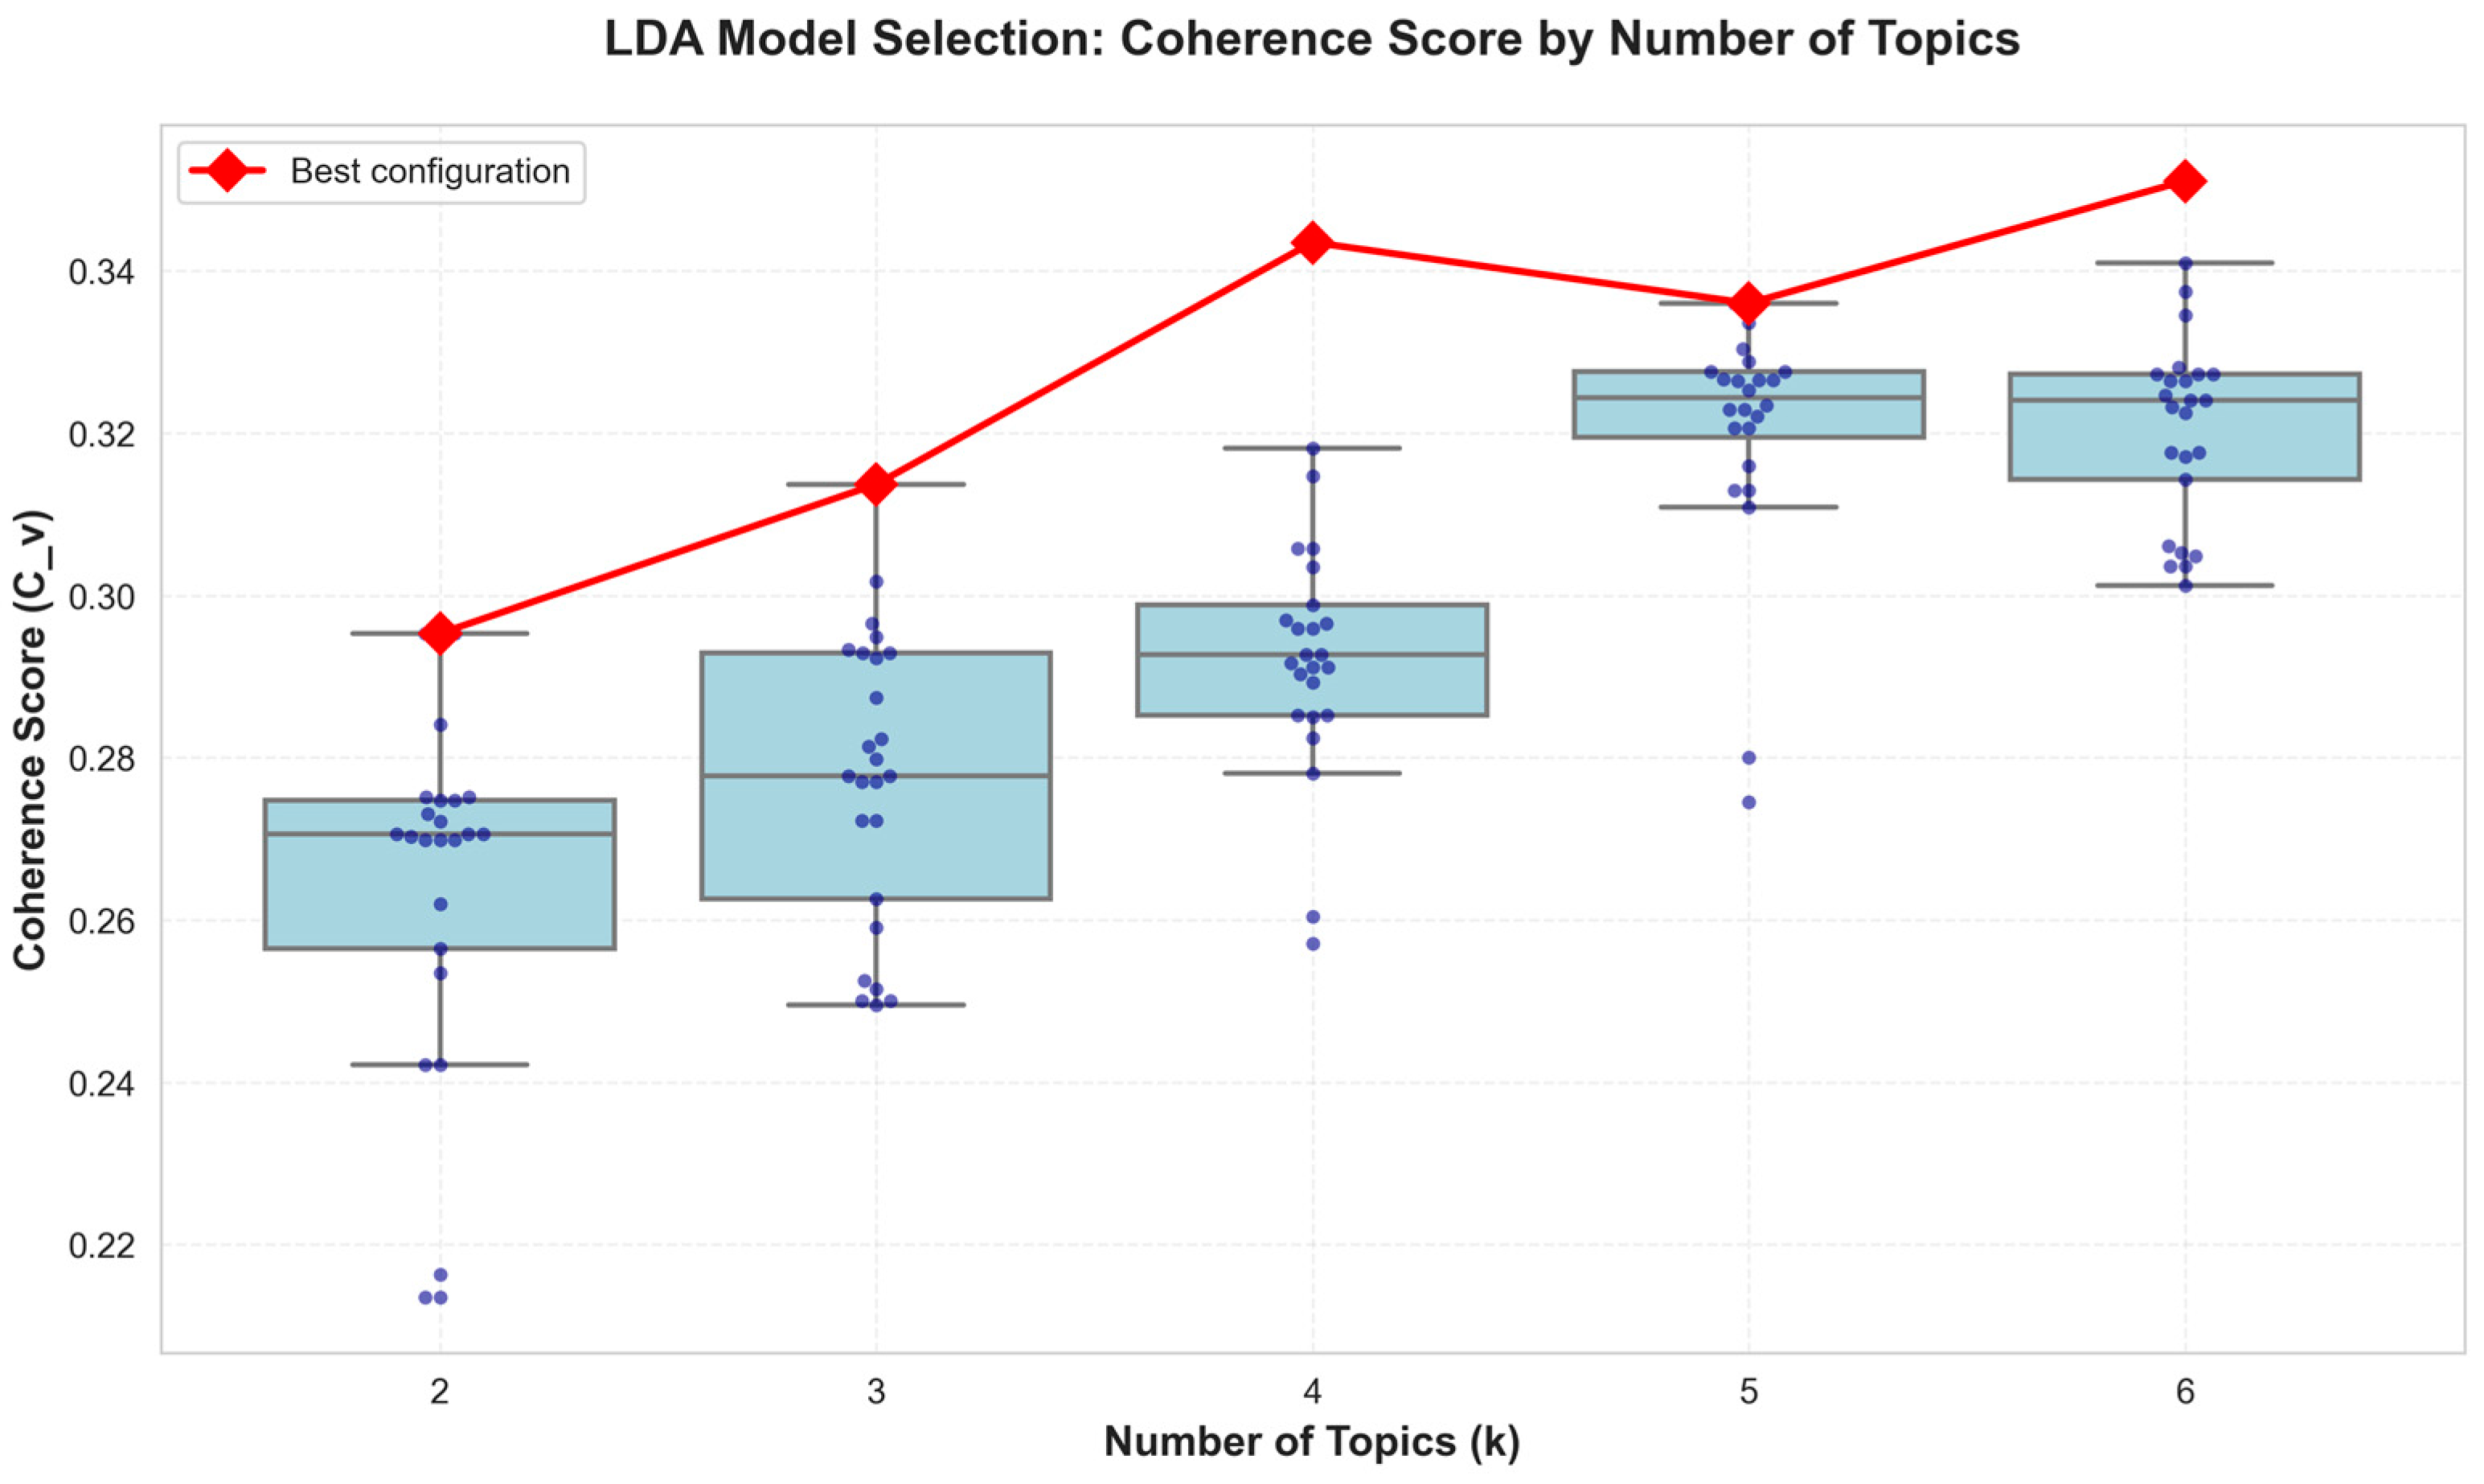
To determine the optimal number of LDA topics, coherence scores (c_v) were computed across a grid of 124 model configurations. The results in Figure 16 are obtained. In this figure, the blue dots represent the individual coherence scores obtained from different LDA runs (e.g., varying random seeds or hyperparameter configurations) for a given number of topics k . Blue boxes summarize the distribution of these scores using boxplots, where the box indicates the interquartile range (IQR), the central line denotes the median coherence score, and the whiskers show the variability outside the upper and lower quartiles. The results depicted in Figure 15 revealed that coherence scores increased with the number of topics, stabilising around k = 5–6. The best-performing model (c_v = 0.351) was obtained with k = 6 topics, α = symmetric, and η = 0.01. Models with fewer topics produced lower coherence, indicating excessively broad topics. The boxplot shows that coherence distributions tighten and improve for k ≥ 4, suggesting that the corpus naturally supports approximately five to six semantically meaningful themes.
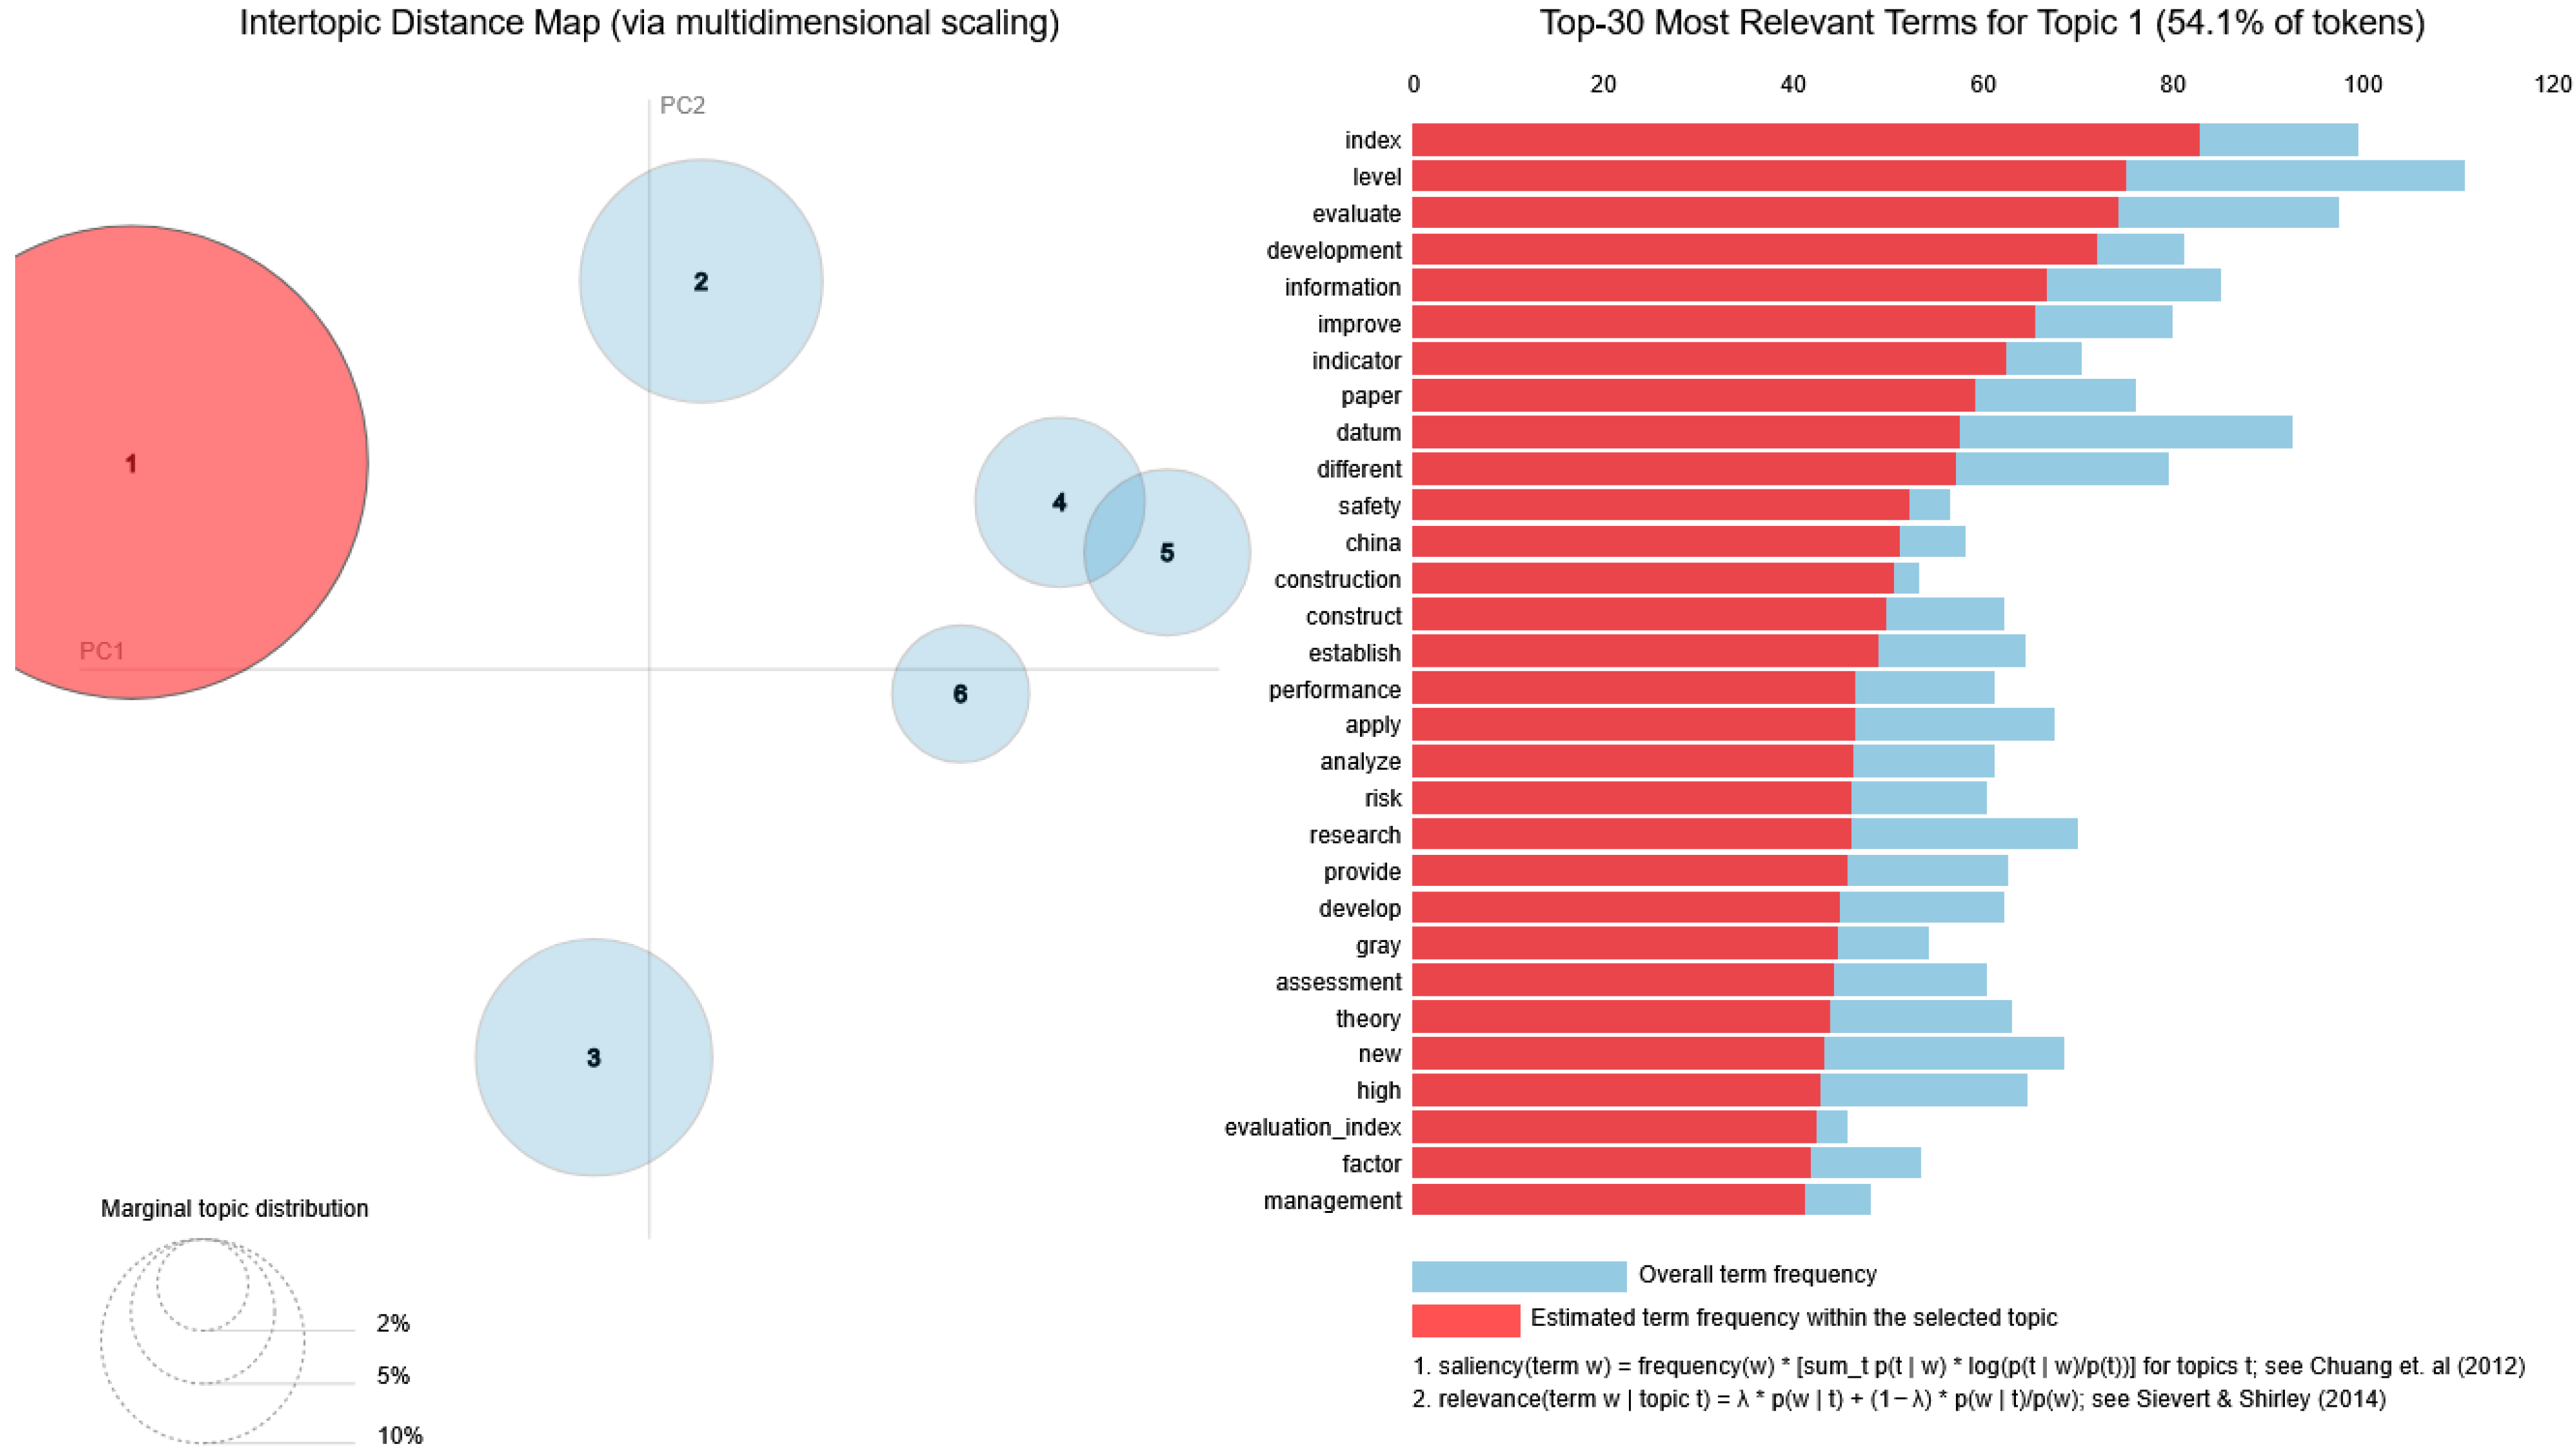
LDA Topic 1 presented in Figure 17 comprises a series of keywords such as index, level, evaluate, development, information, improve, indicator, paper, datum, safety, construction, performance, risk, assessment, theory, and management and represents the largest cluster, accounting for 54.1% of the tokens. Based on the listed keywords, it can be observed that this topic combines terms related to evaluation indices, assessment methods, and applications in construction/safety/management, with a large focus on the methodological frameworks and performance evaluation using grey clustering.
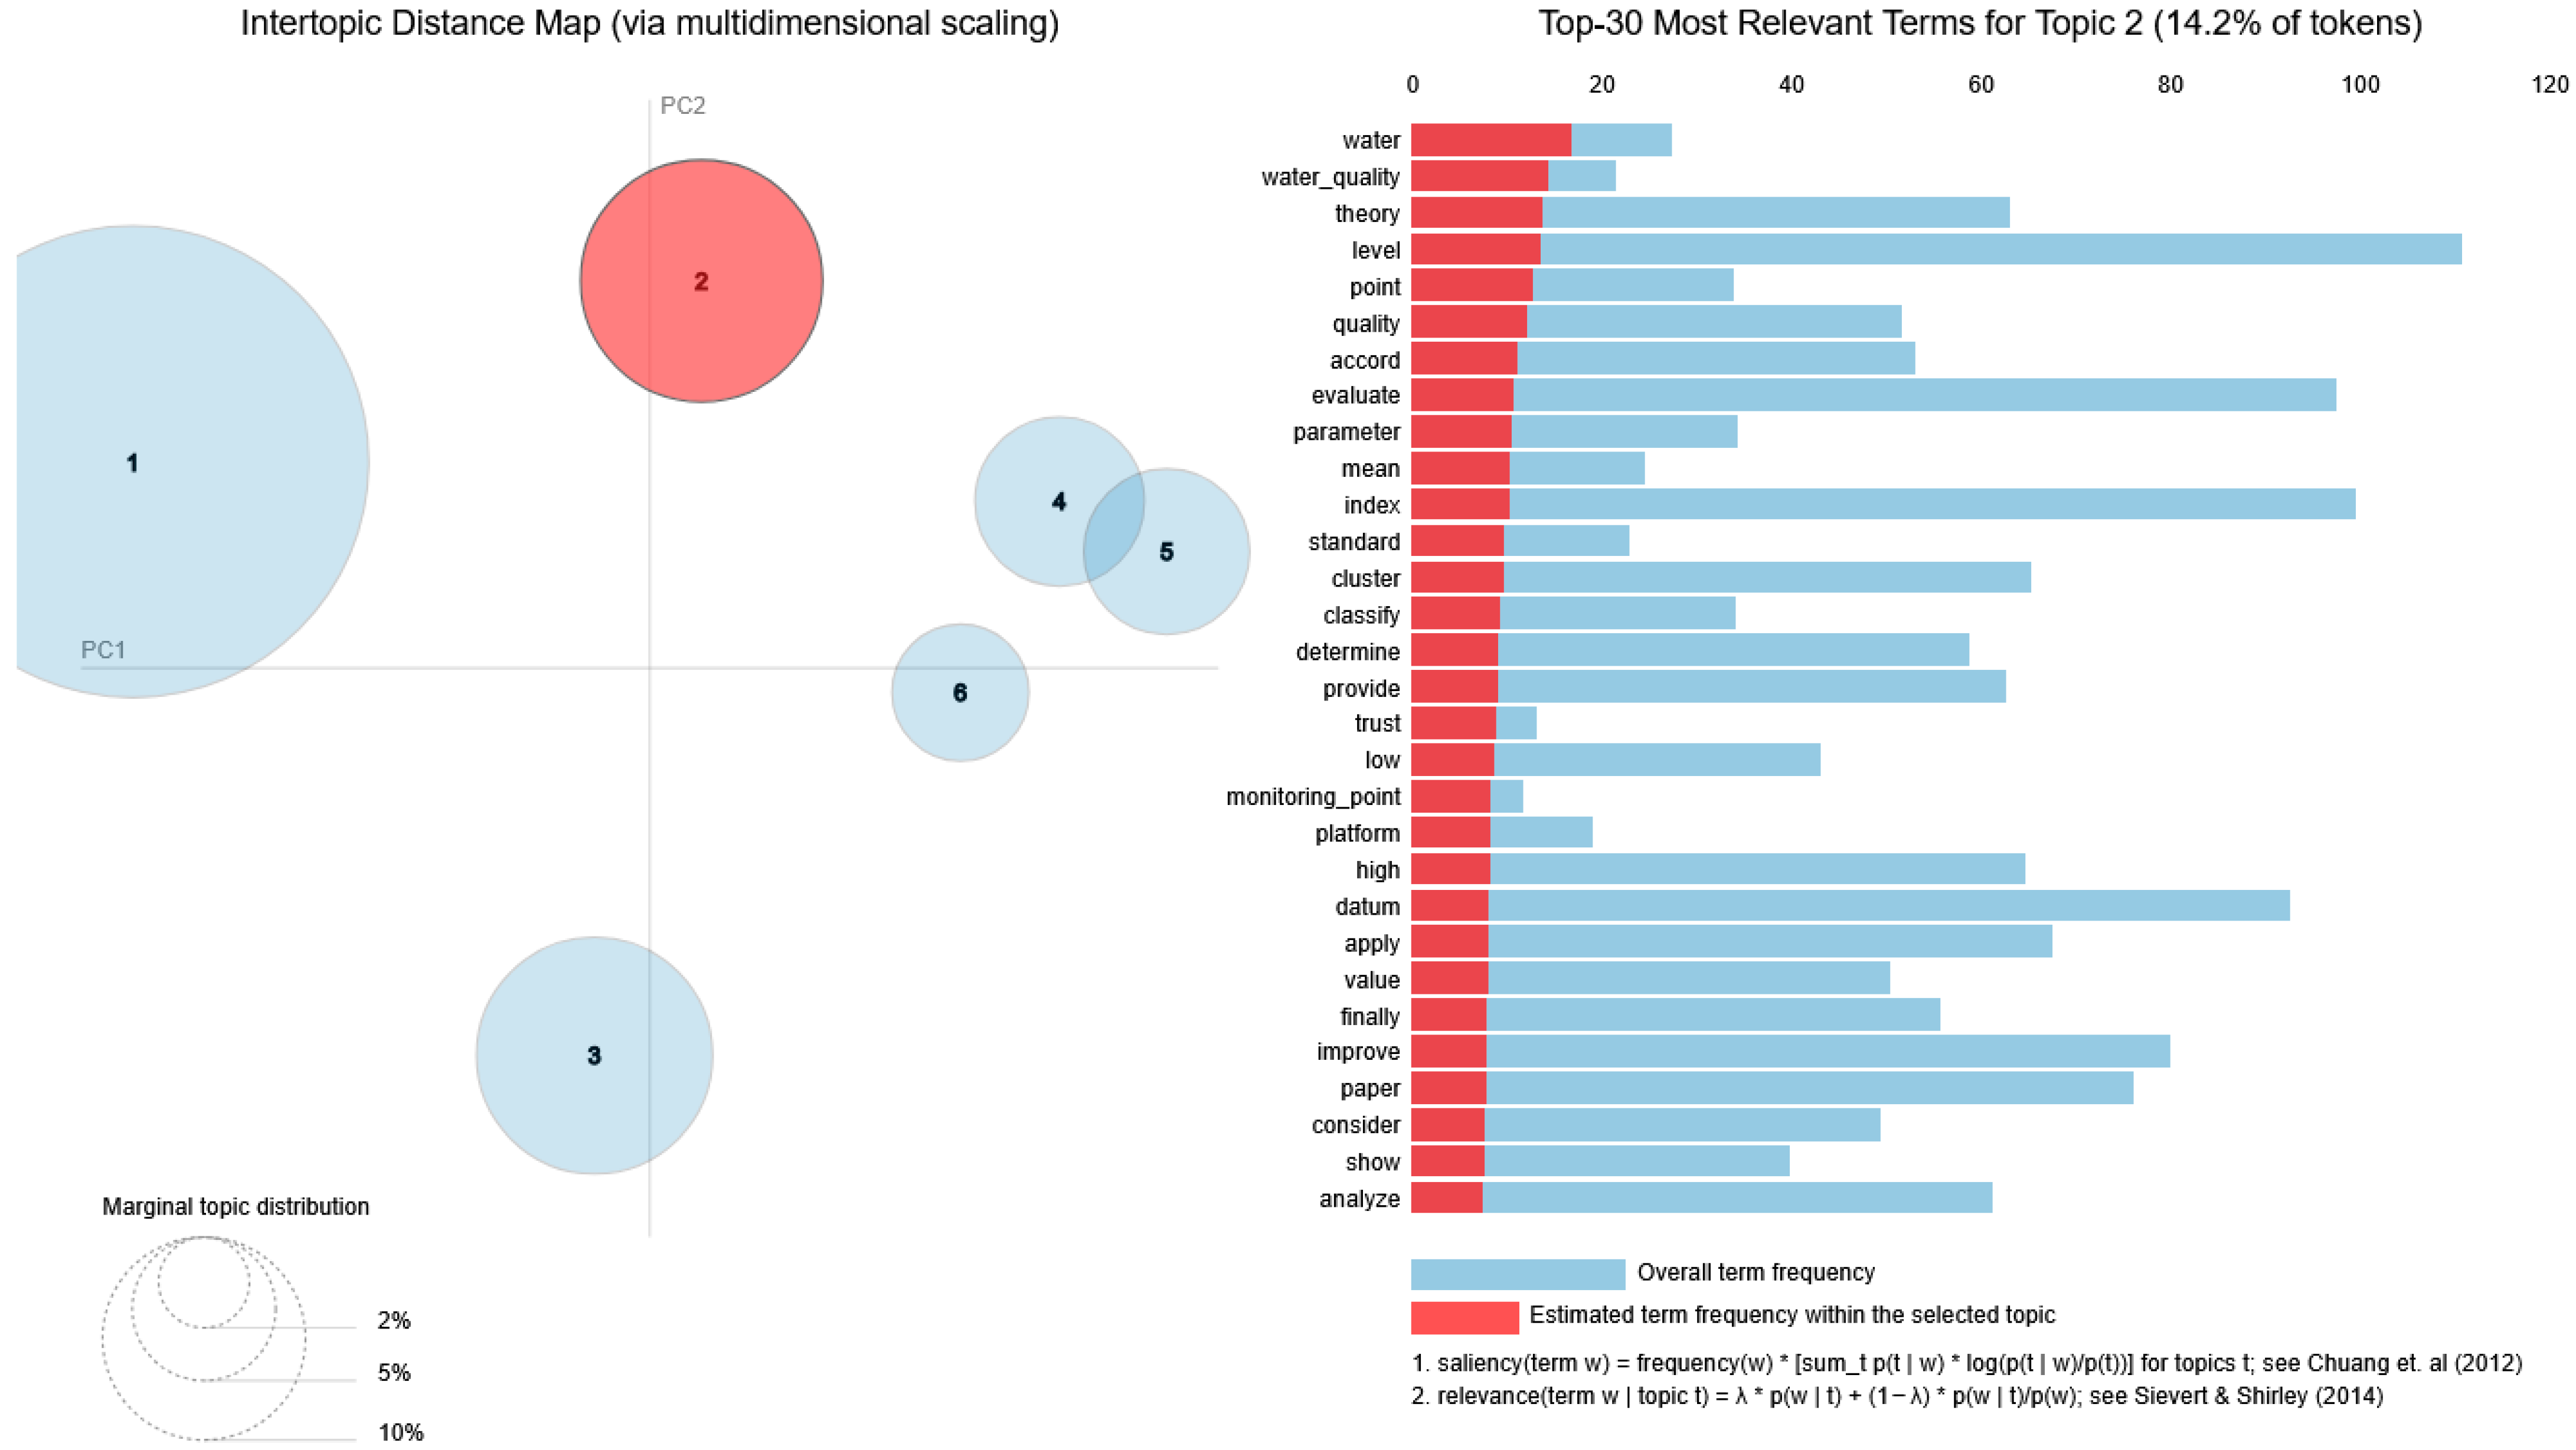
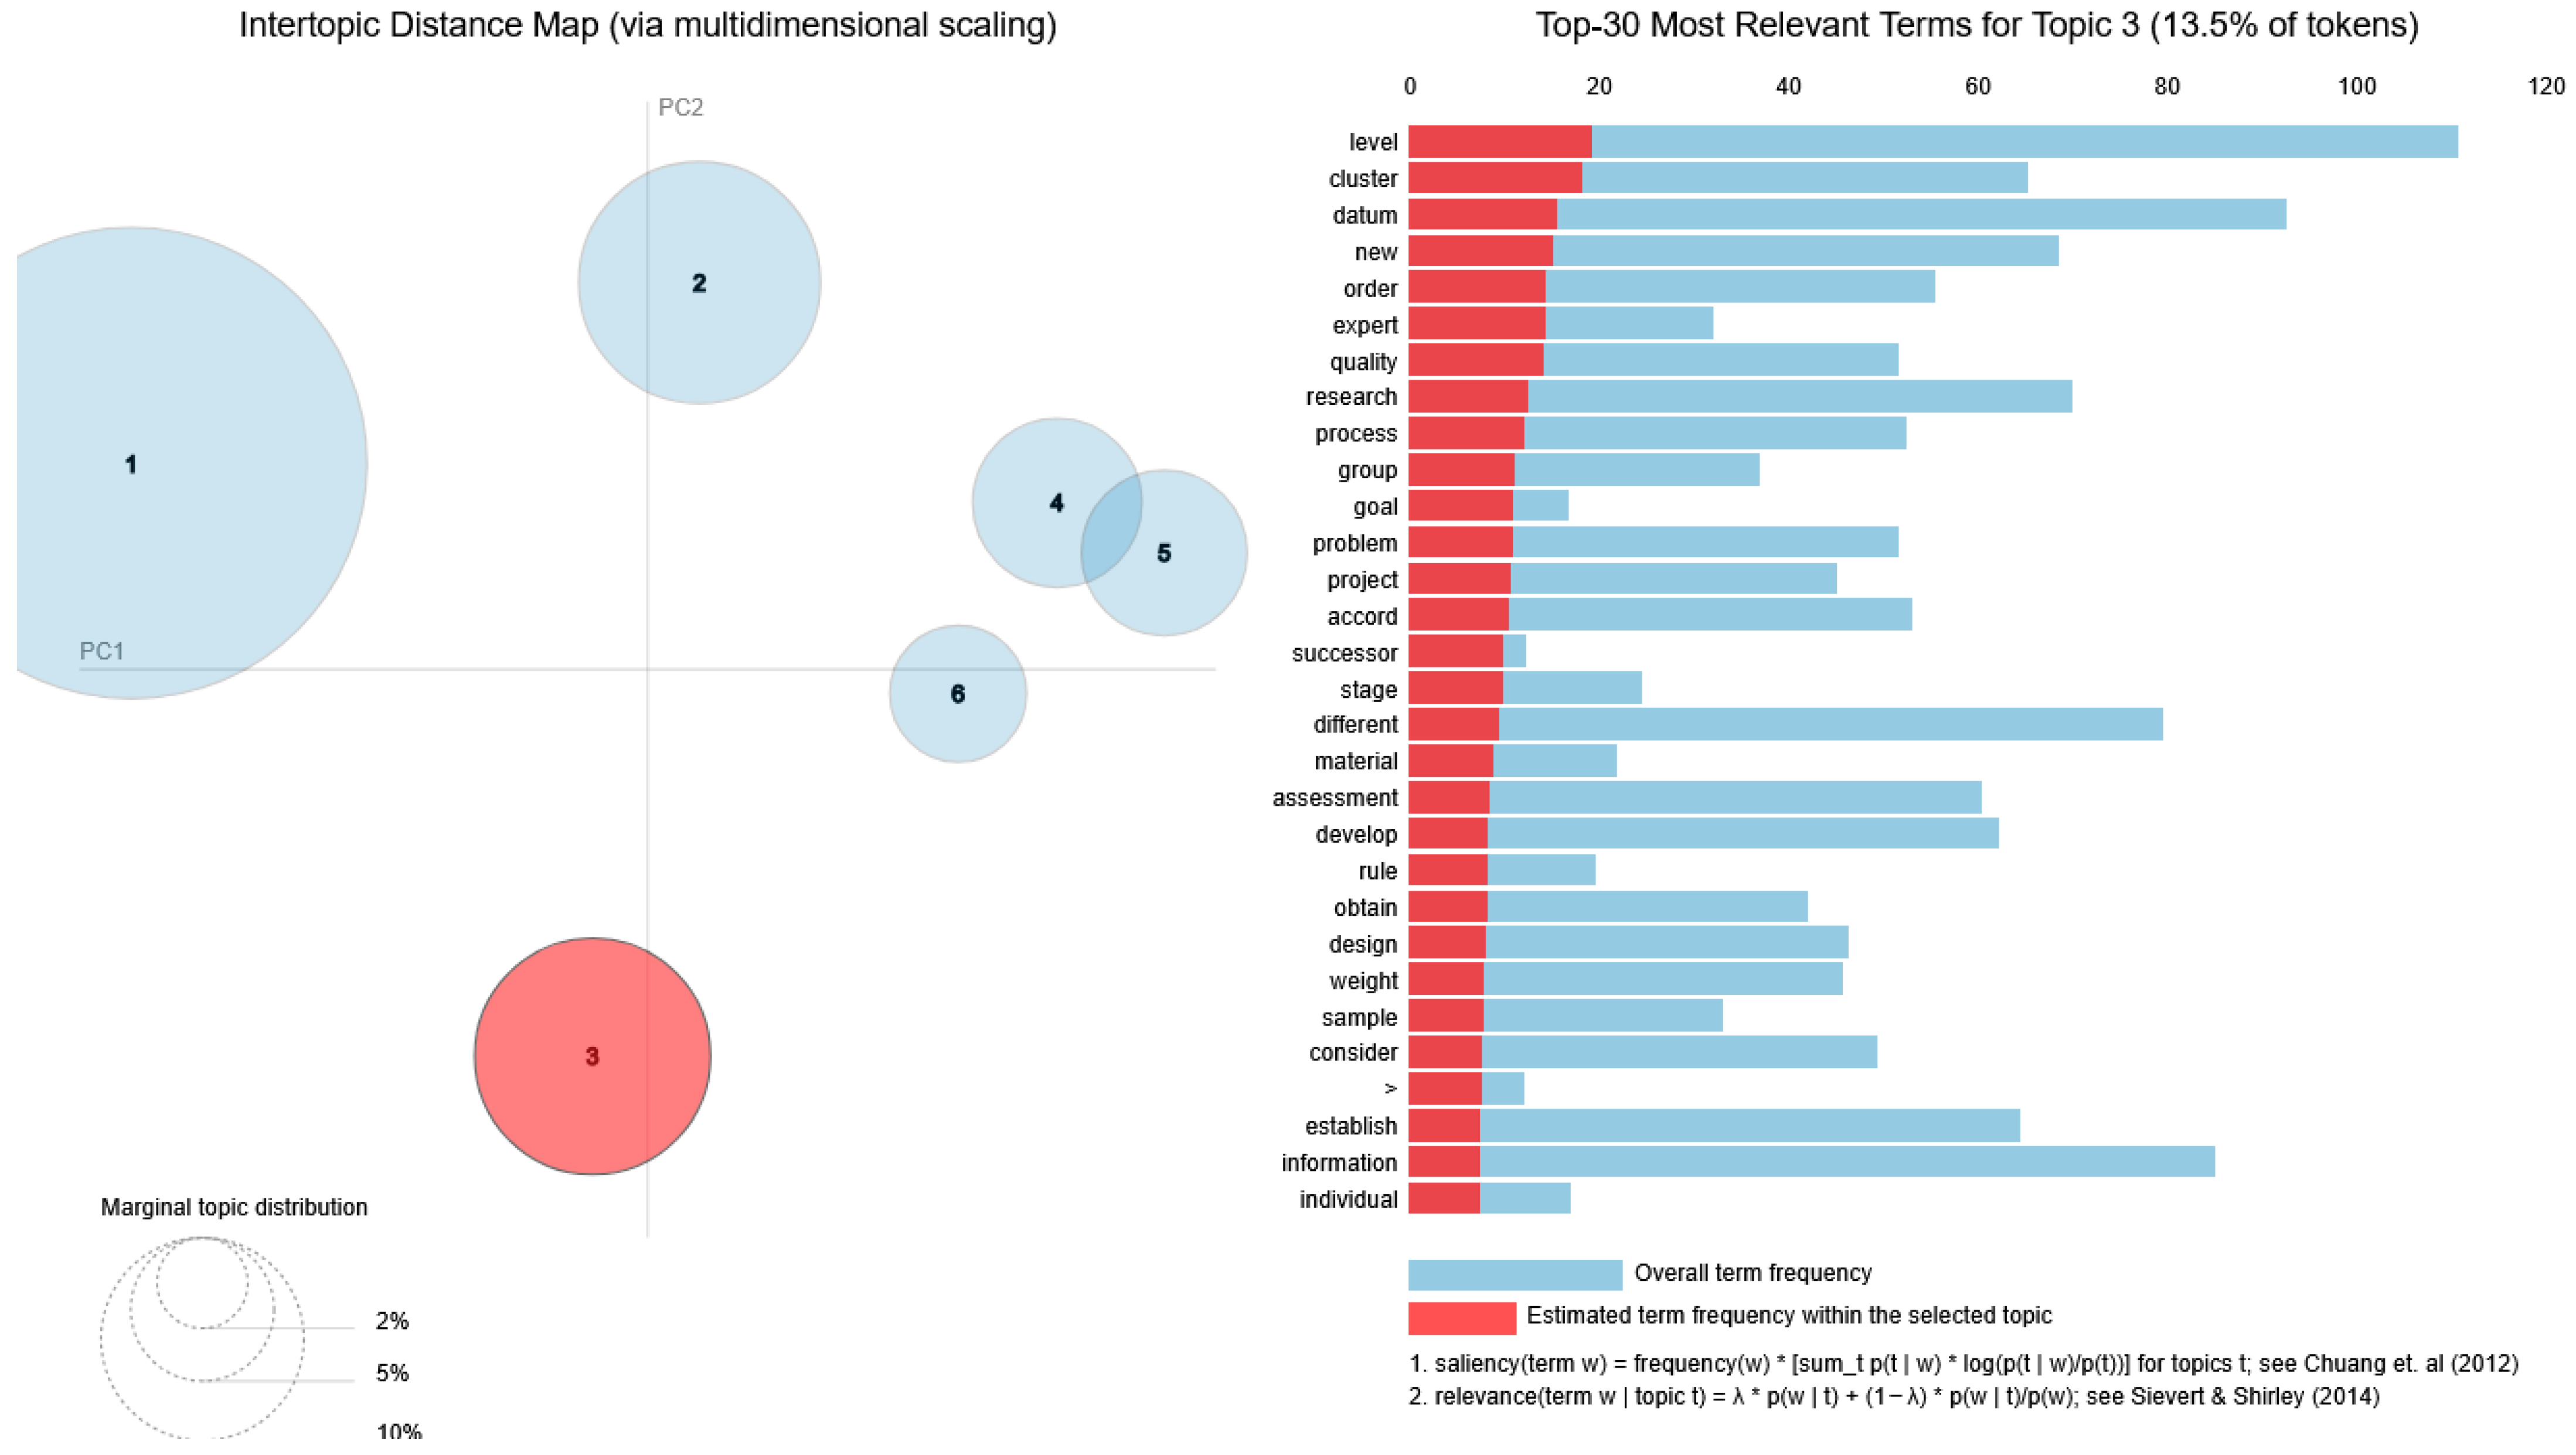
LDA Topic 2 (Figure 18) and LDA Topic 3 (Figure 19) retain comparable percentages of the tokens, namely 14.2%, respectively, 13.5%. In the case of LDA Topic 2, the main keywords are represented by water, water_quality, monitoring_point, parameter, standard, cluster, classify, evaluate, trust, index, and quality, which suggest a focus on environmental and water quality monitoring, with applications of grey clustering to classify and evaluate ecological or quality parameters. On the other hand, LDA Topic 3 gravitates around research methodology and expert-based decision-making in areas connected with project evaluation, design processes, and problem-solving frameworks, as it encompasses keywords such as datum, expert, process, problem, project, successor, material, design, rule, assessment, and research.
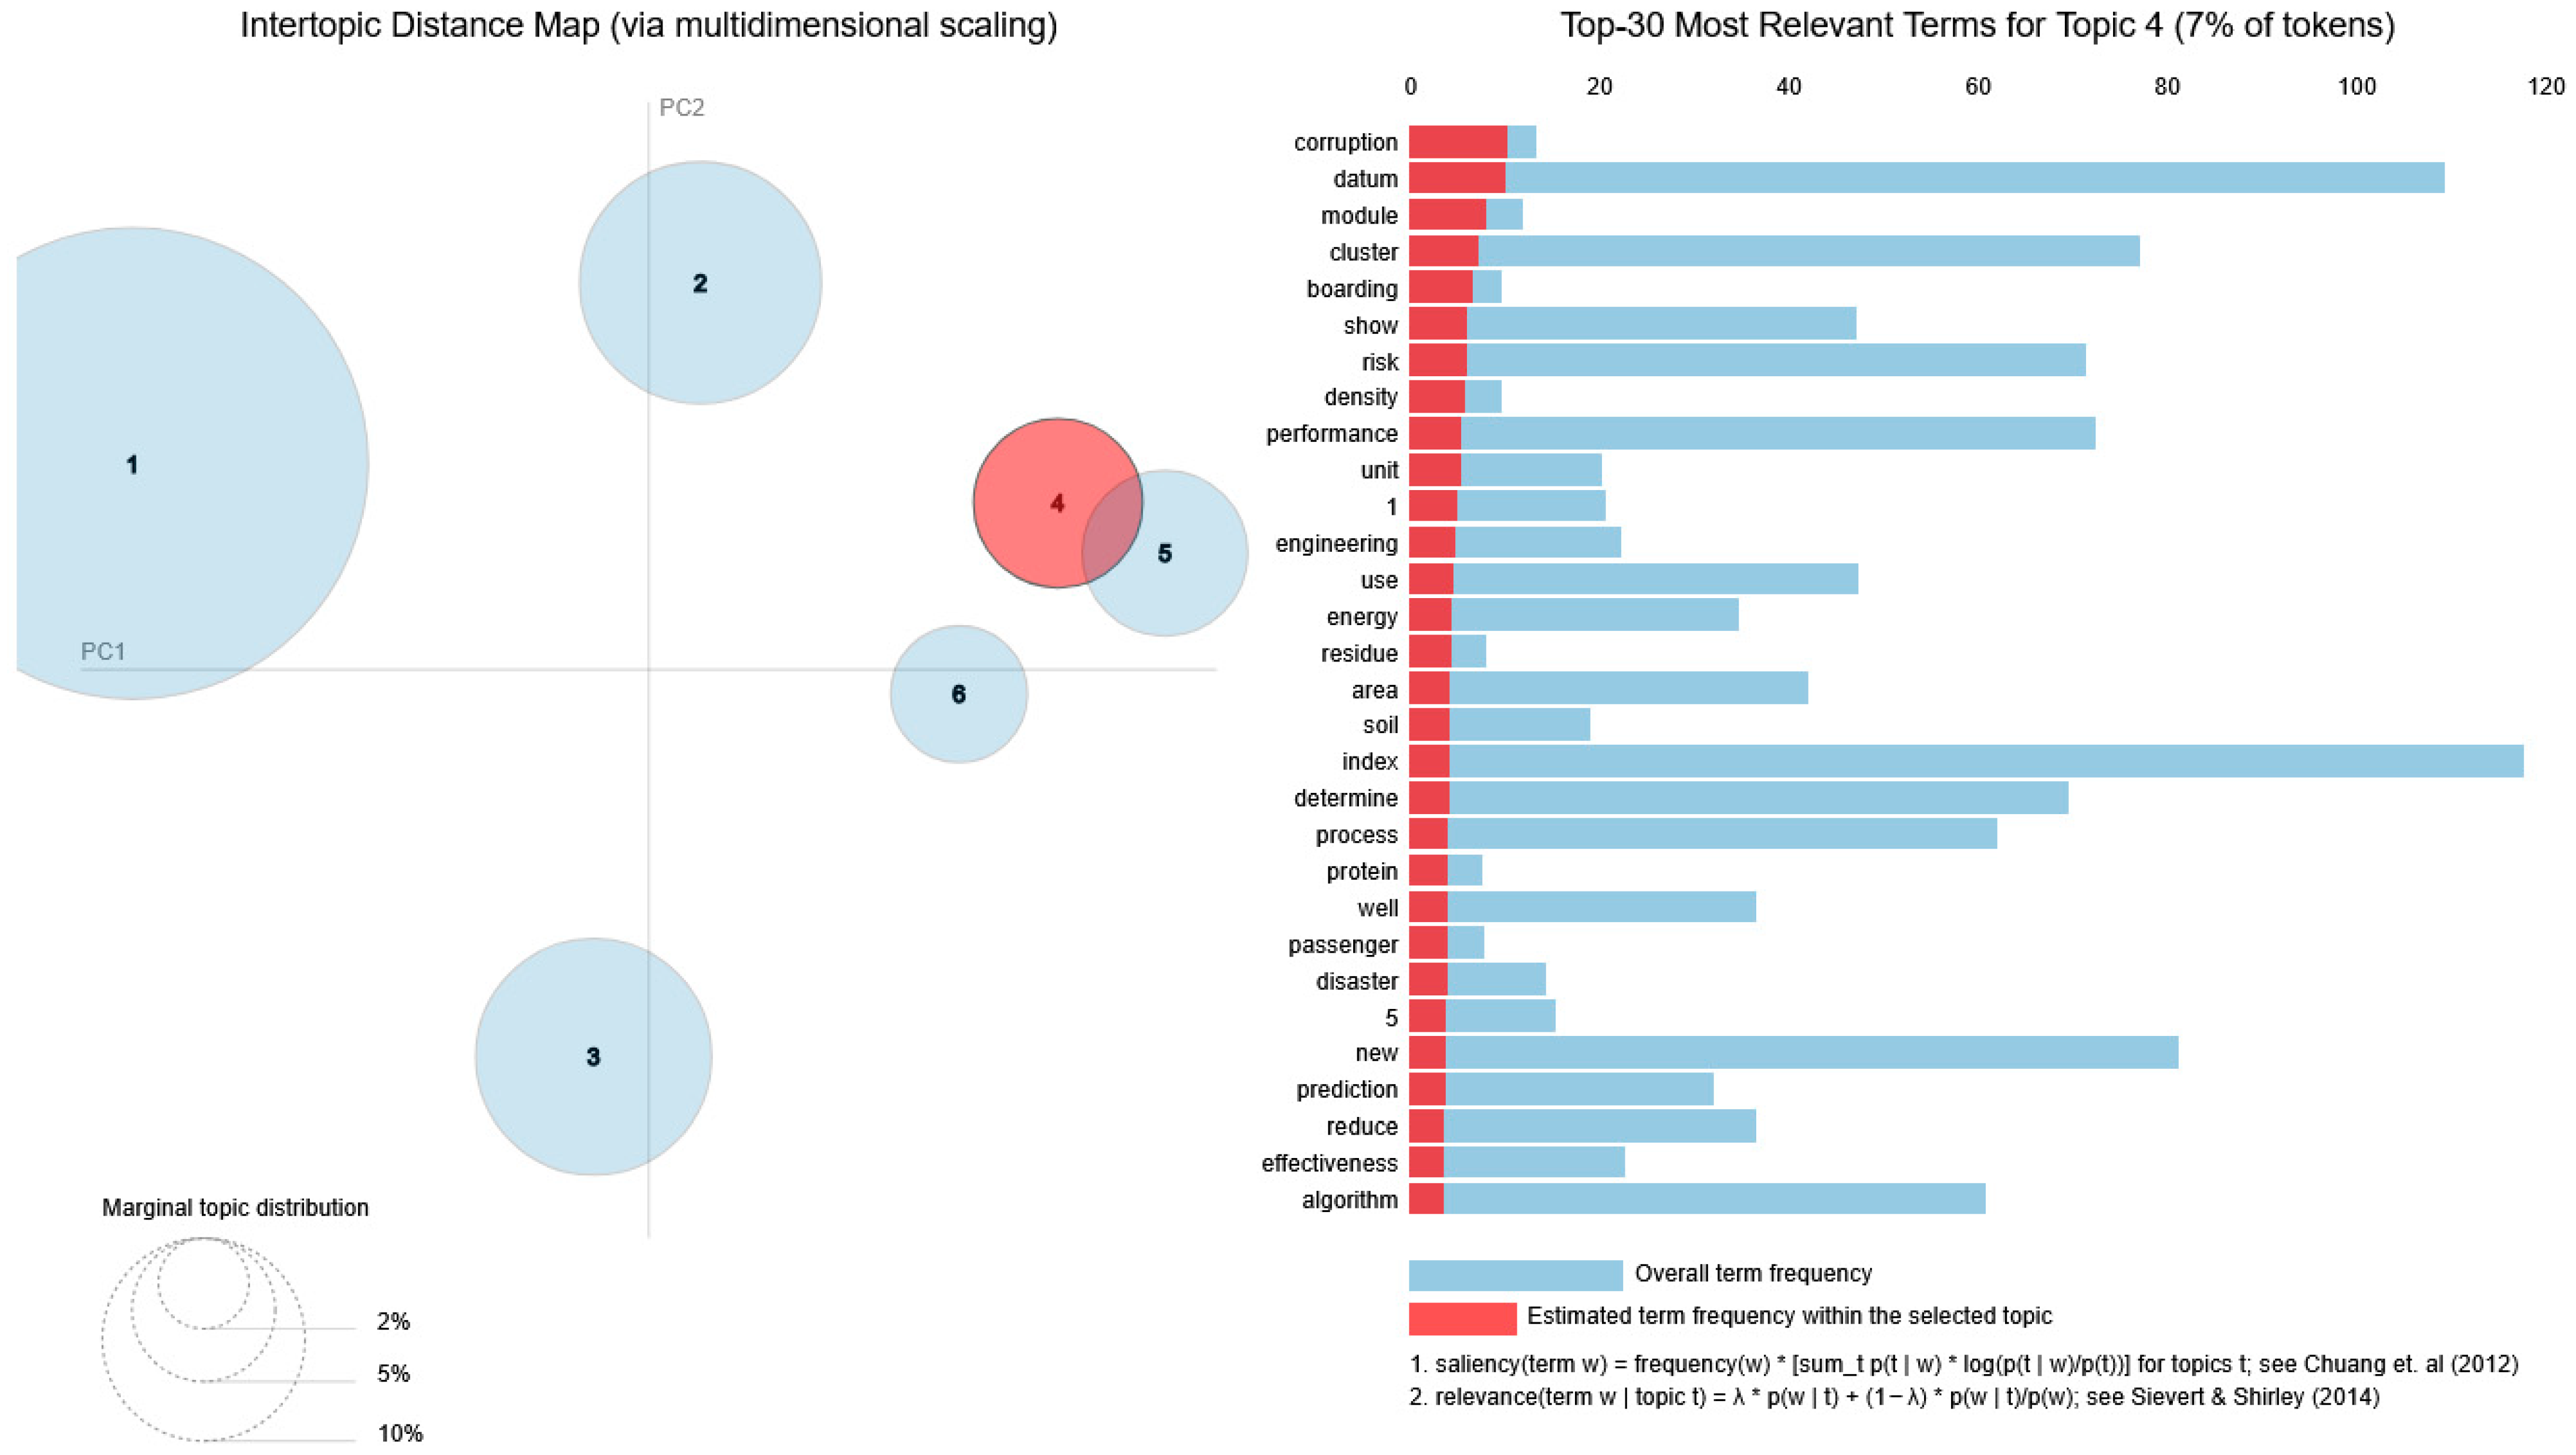
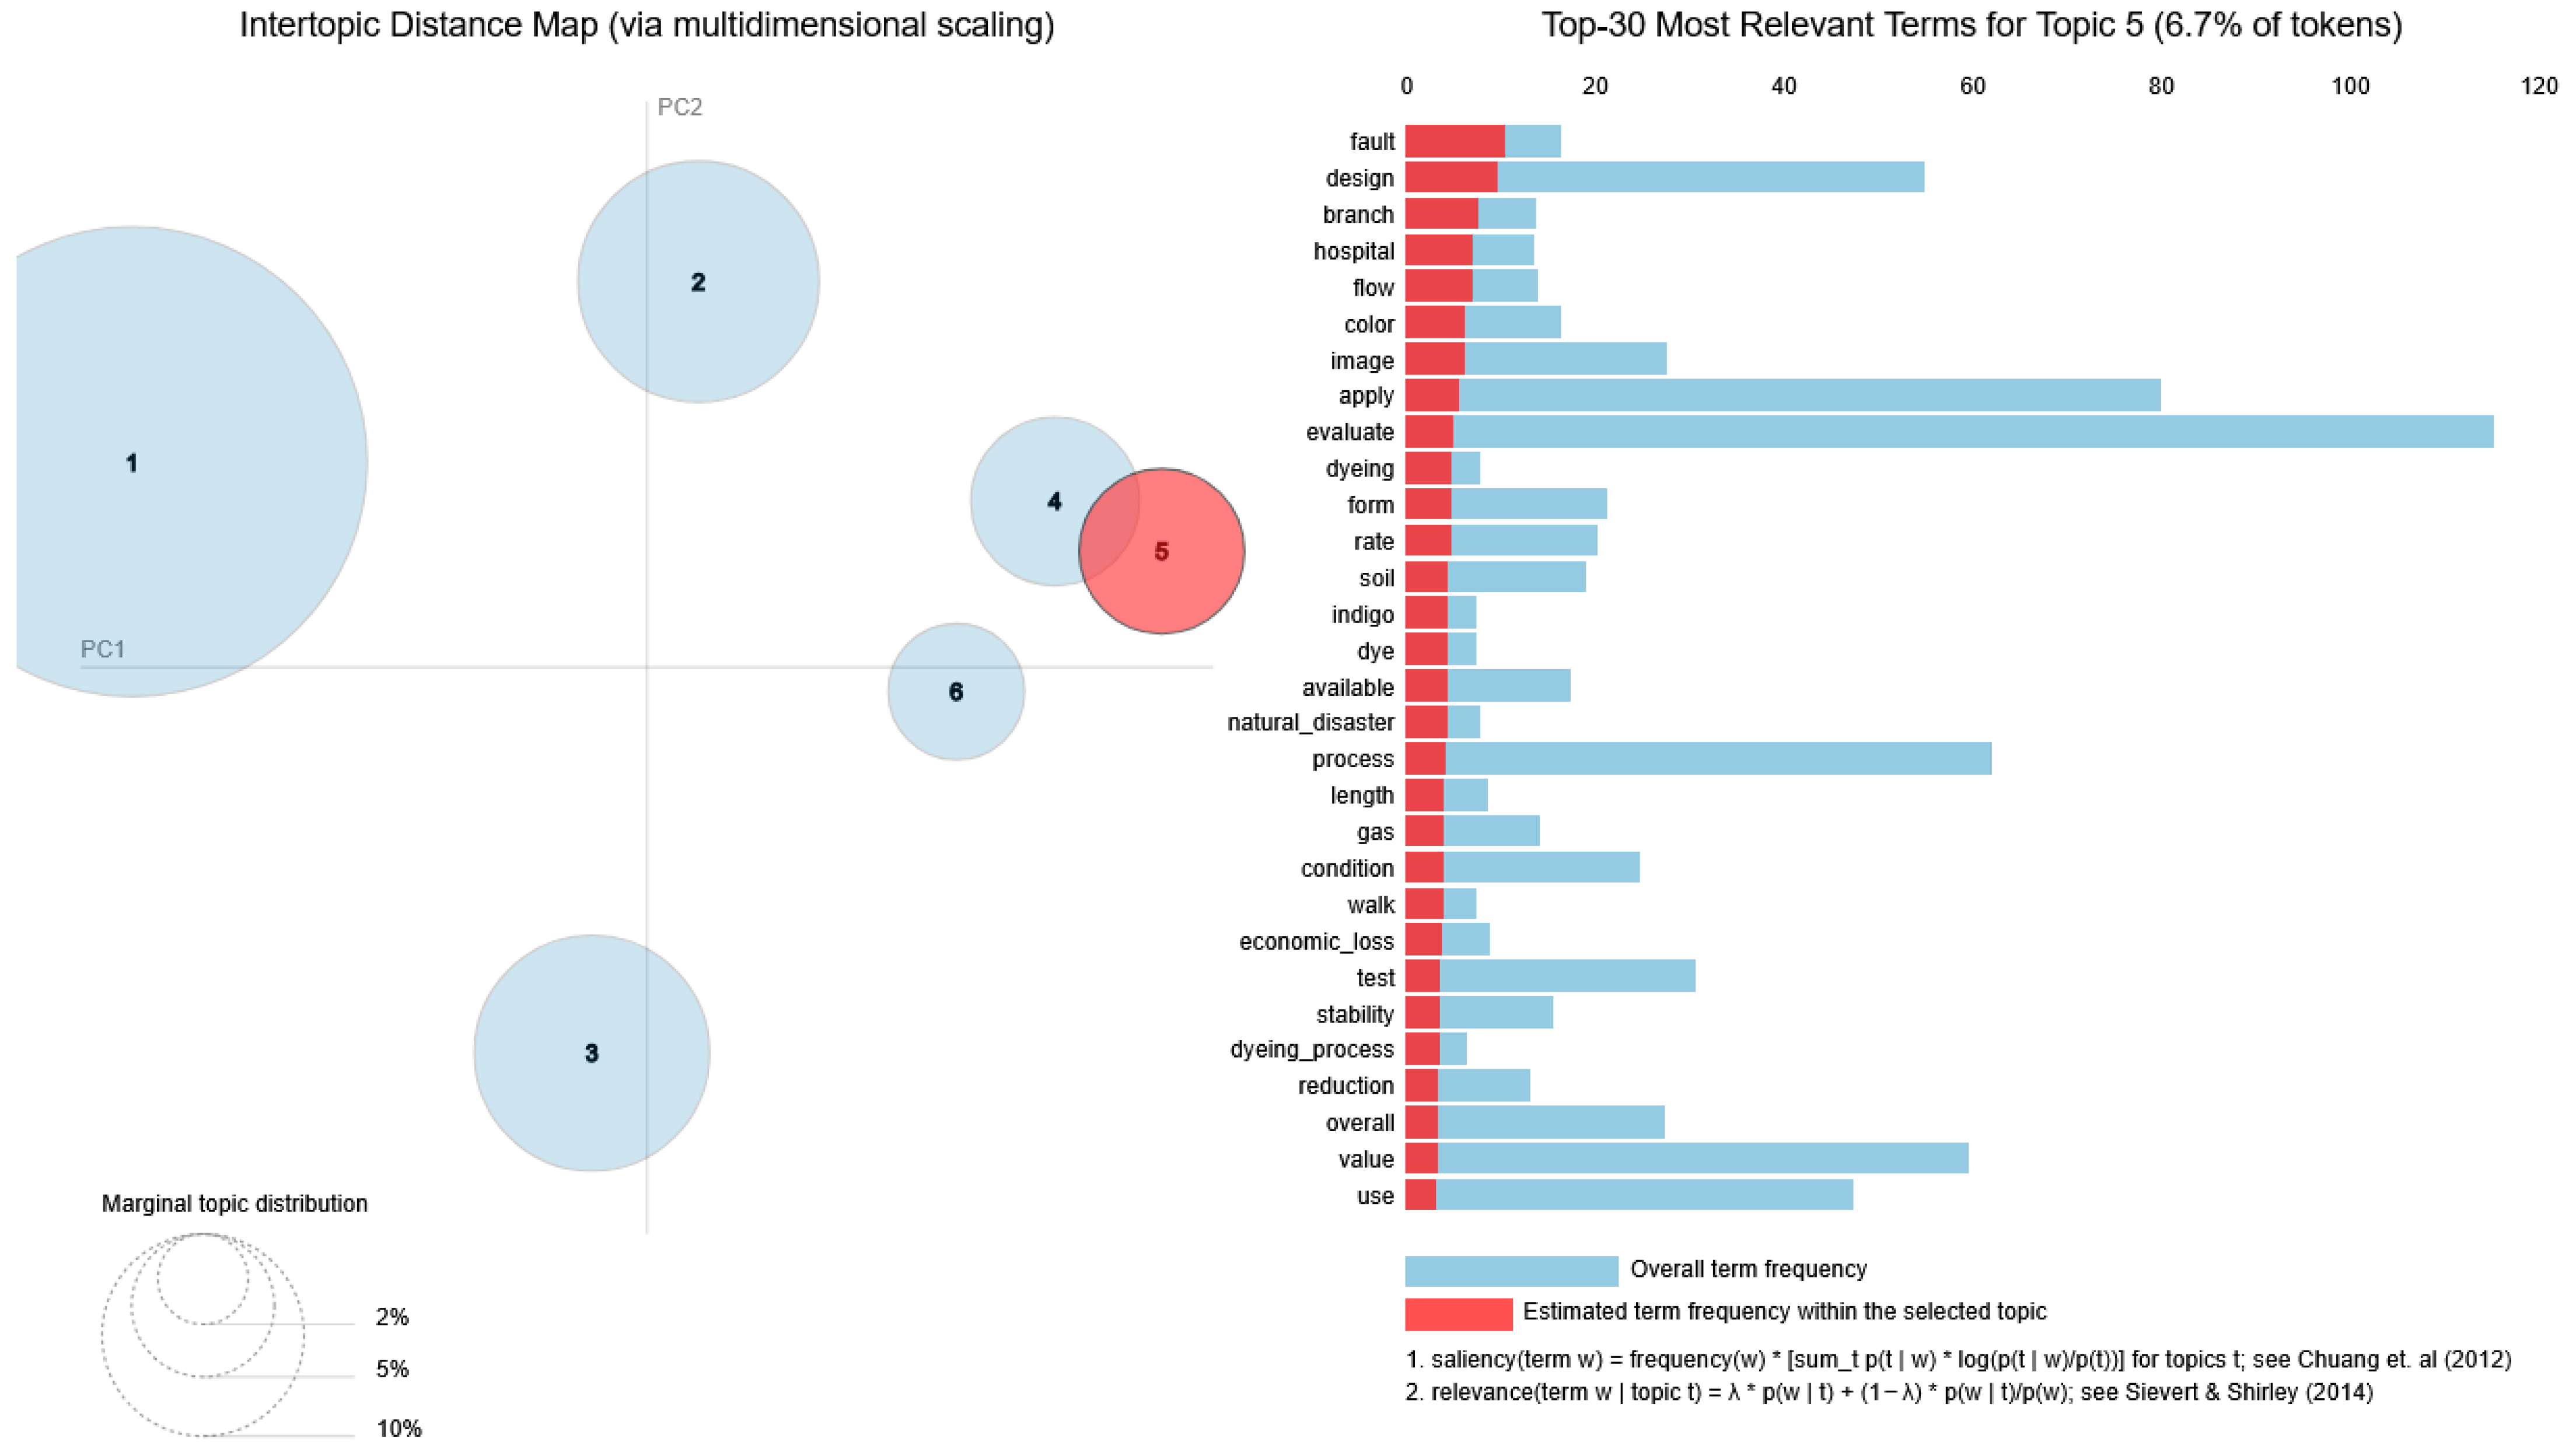
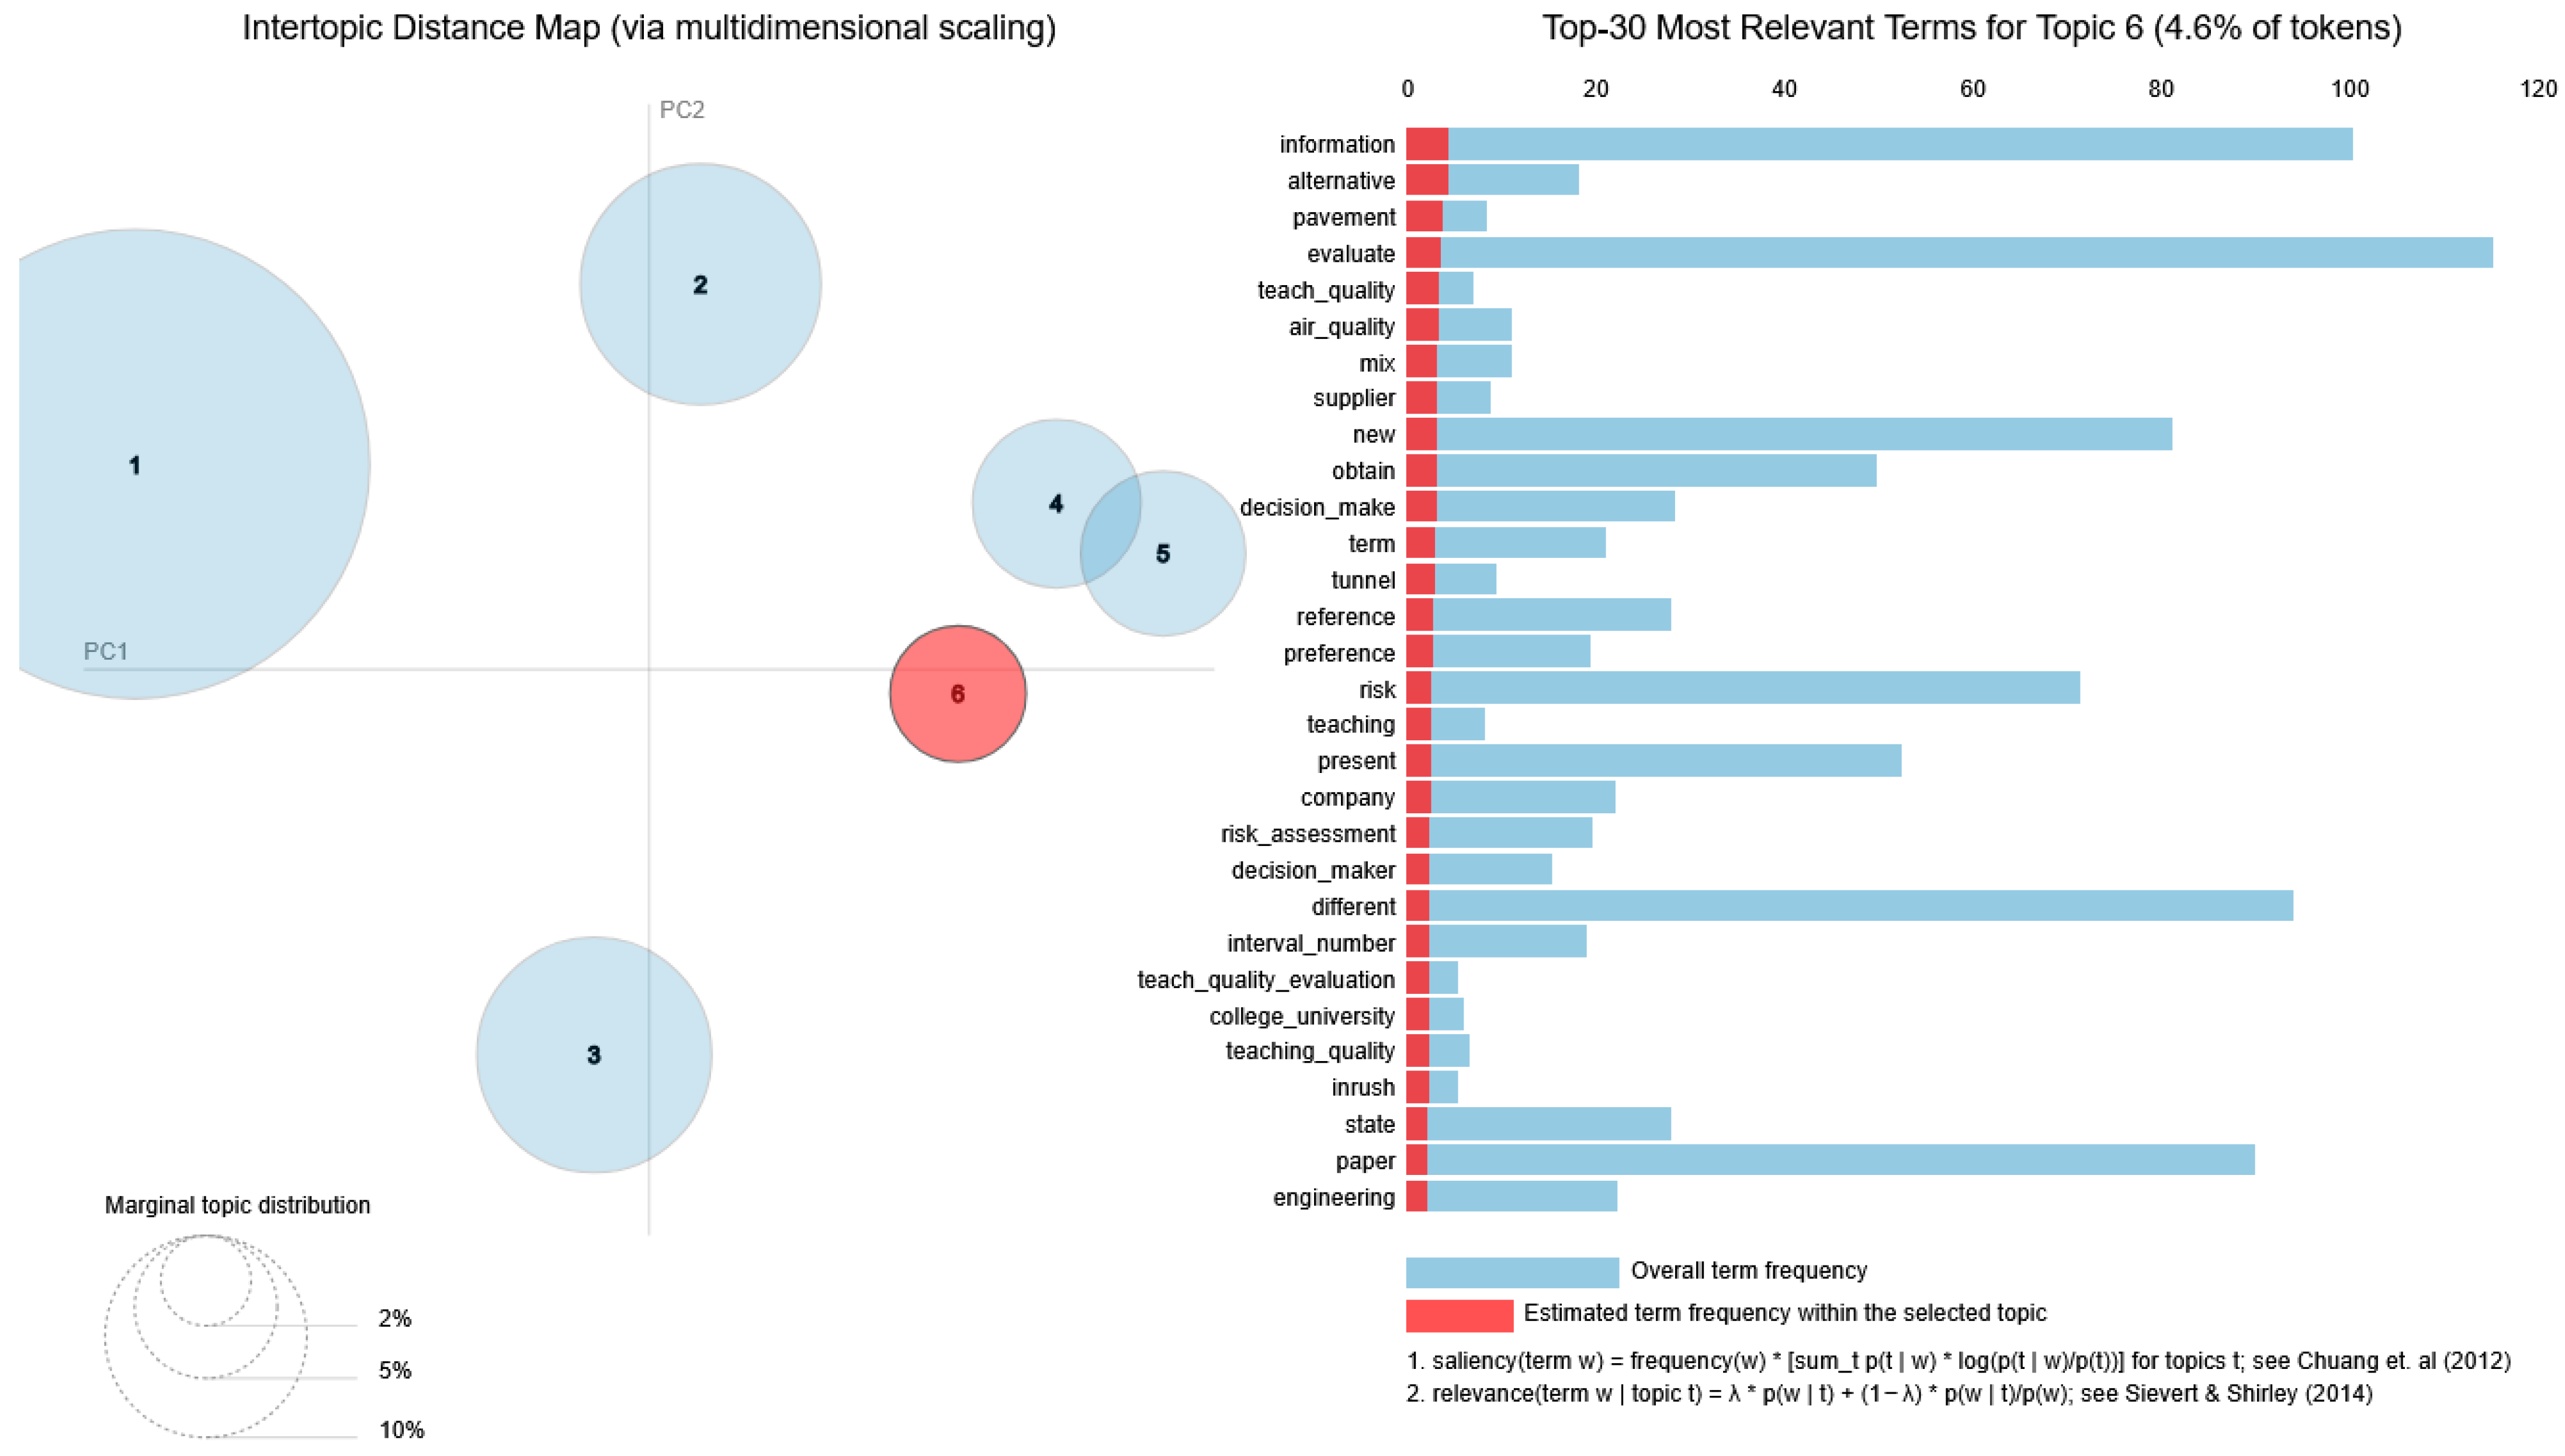
The remainder of the identified topics provides a smaller retention of the tokens, ranging from 4.6% in the case of LDA Topic 6 to 7% in the case of LDA Topic 4 (Figure 20, Figure 21 and Figure 22).
LDA Topic 4 has a focus on grey clustering research in connection with elements related to risk assessment. As a result, it is expected that a series of papers included here follow this line by assessing the risk in various research areas, such as, but not limited to, airplane boarding in times of COVID-19, disaster in engineering systems, and corruption studies. The keywords associated with this topic that support the mentioned research directions are corruption, module, boarding, risk, performance, engineering, disaster, soil, energy, and algorithm (Figure 20).
LDA Topic 5 retains 6.7% of the tokens and includes keywords such as fault, hospital, flow, image, apply, evaluate, dyeing, indigo, natural_disaster, economic_loss, test, and process, thus focusing on research dedicated to applications of the grey clustering into healthcare (hospital, flow), natural disasters, textile/dyeing processes, and industrial testing.
Lastly, LDA Topic 6 appears as a supporting/mixed methods cluster, focusing on decision-making modules, engineering solutions, and soil/environmental factors, featuring keywords such as decision_make, module, soil, order, alternative, expert, and engineering.
Considering the keywords associated with each of the six topics discussed above and identified through the LDA, it can be observed that the LDA topics are as follows: LDA Topic 1, Grey Clustering for Performance Evaluation and Decision-Making Frameworks; LDA Topic 2, Grey Clustering in Environmental and Water Quality Assessment; LDA Topic 3, Grey Clustering in Expert Systems and Project Evaluation; LDA Topic 4, Grey Clustering for Risk Assessment and Socio-Technical Systems; LDA Topic 5, Grey Clustering in Healthcare, Industrial Processes, and Disaster Impact Evaluation; and LDA Topic 6, Grey Clustering for Multi-Criteria Decision-Making in Engineering and Environment.
As observed in the above-identified topics, grey clustering succeeds in demonstrating both methodological advances and a wide range of practical applications.
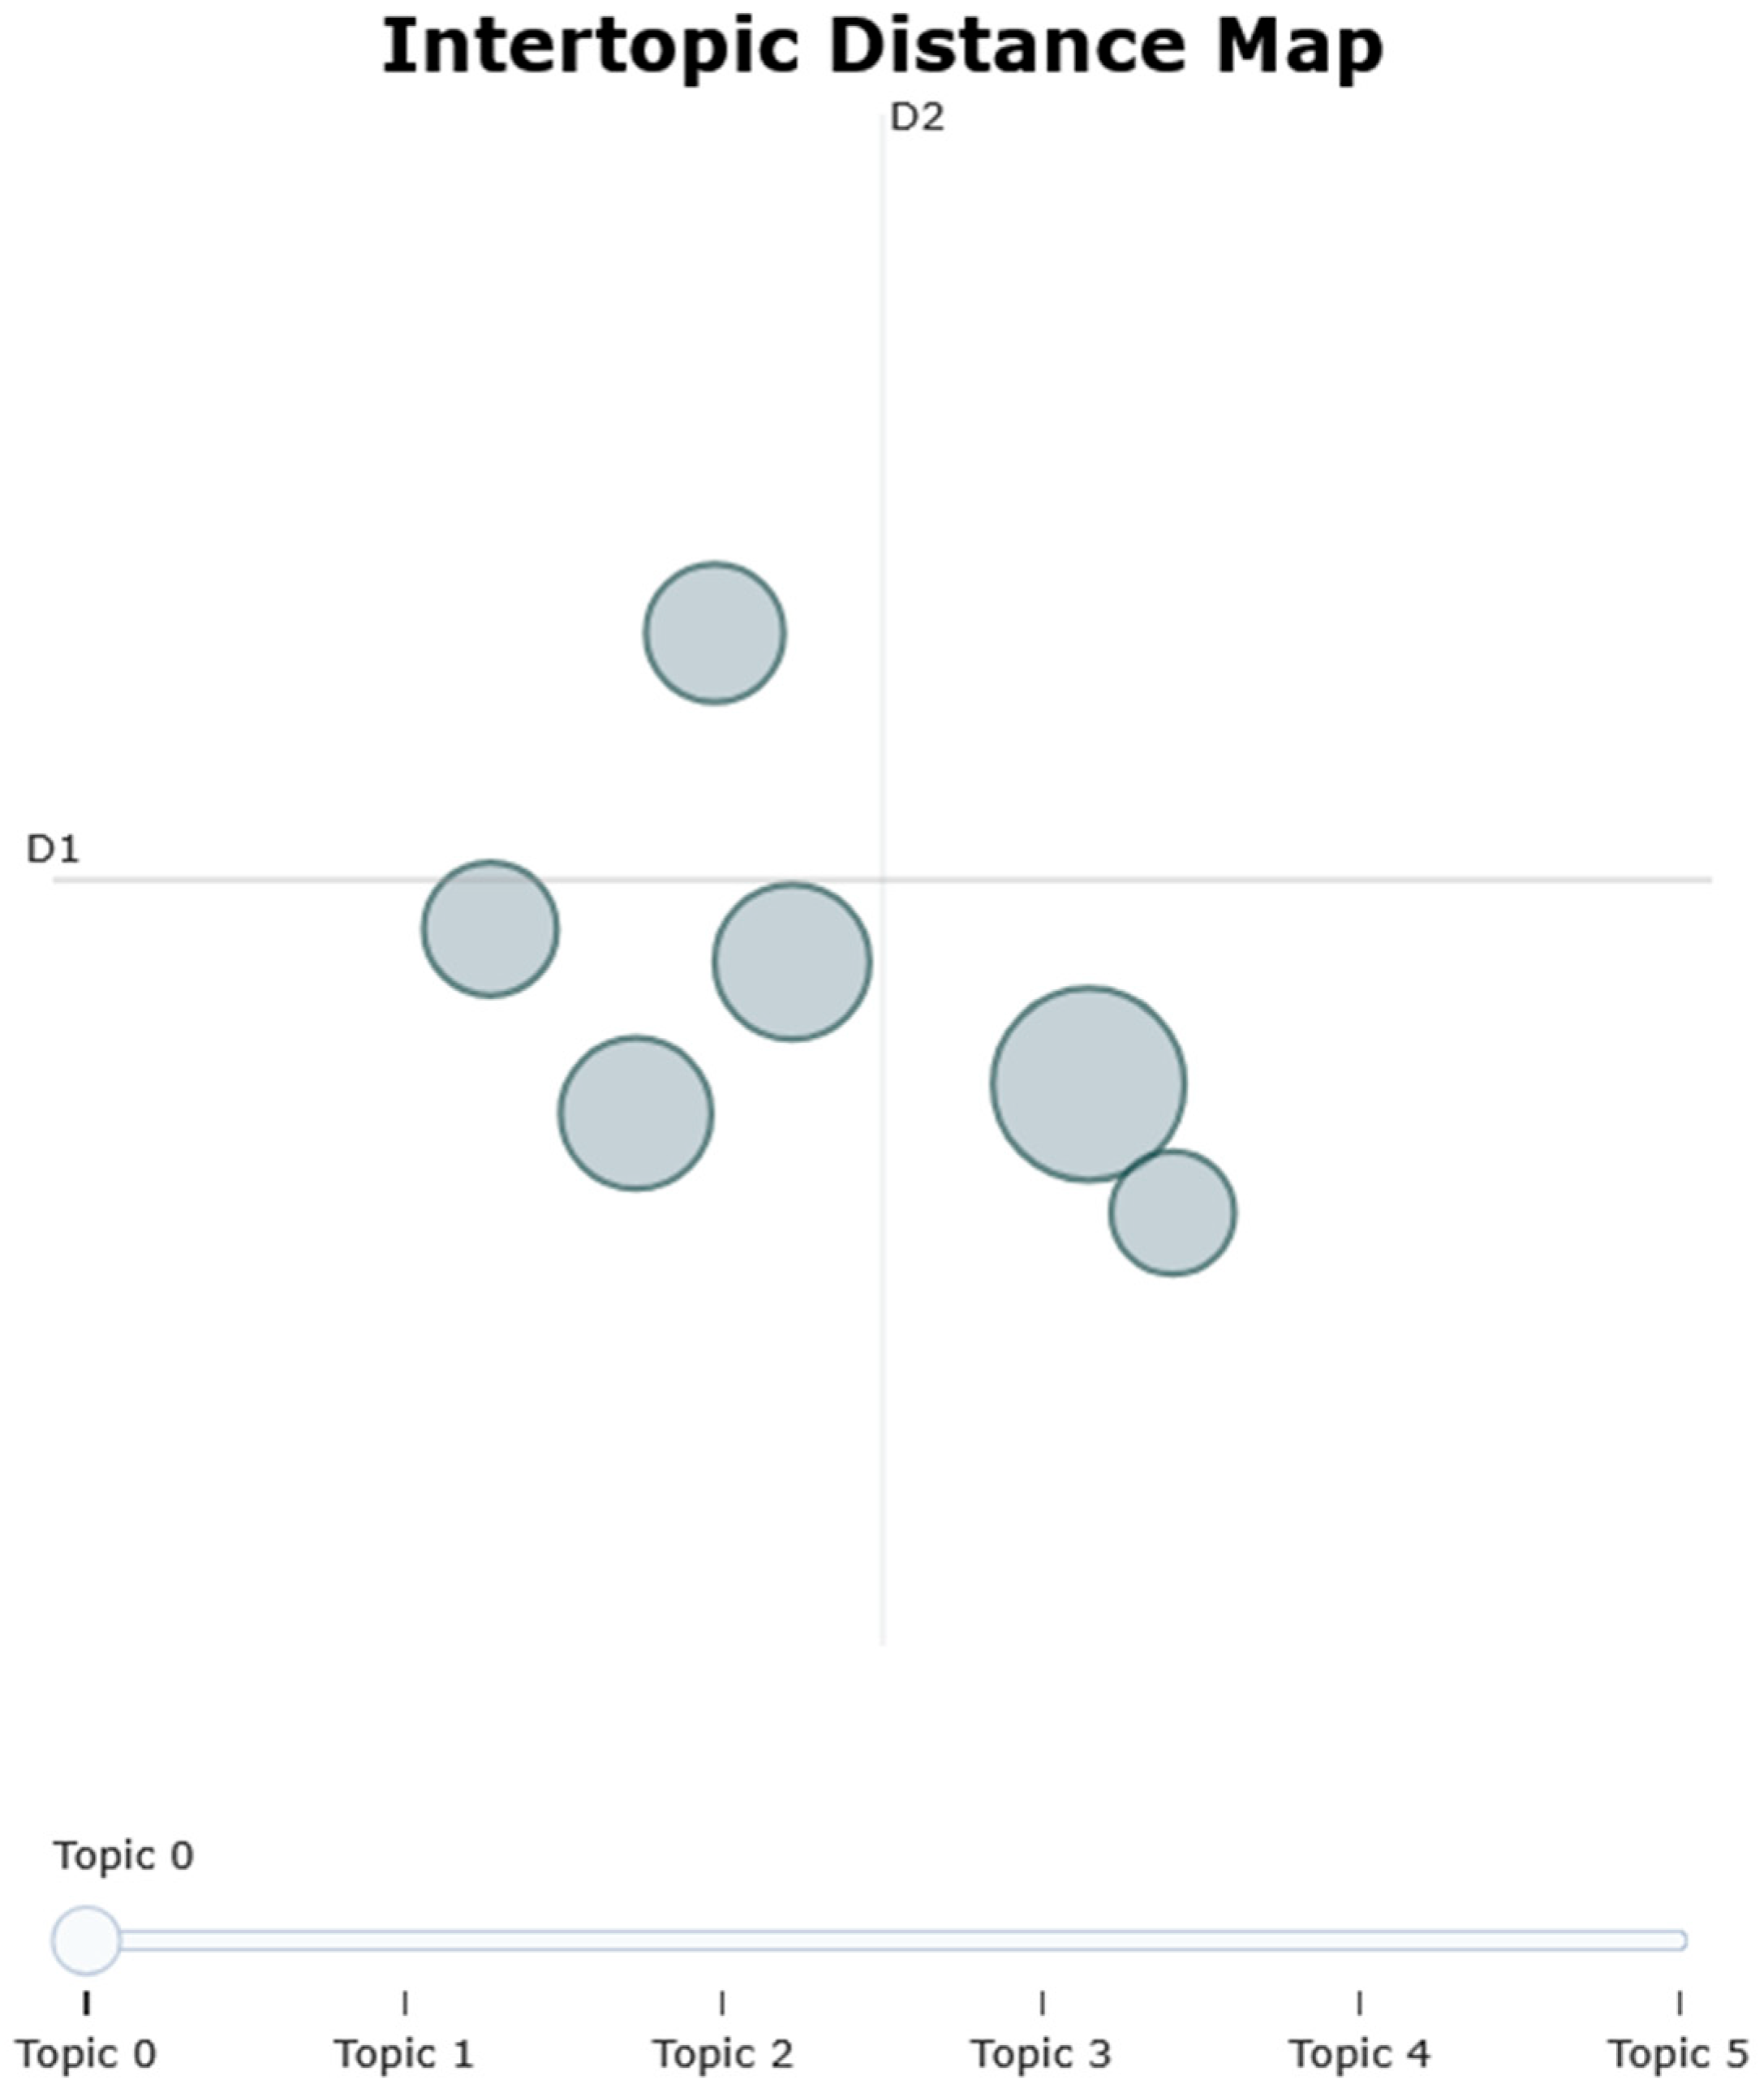
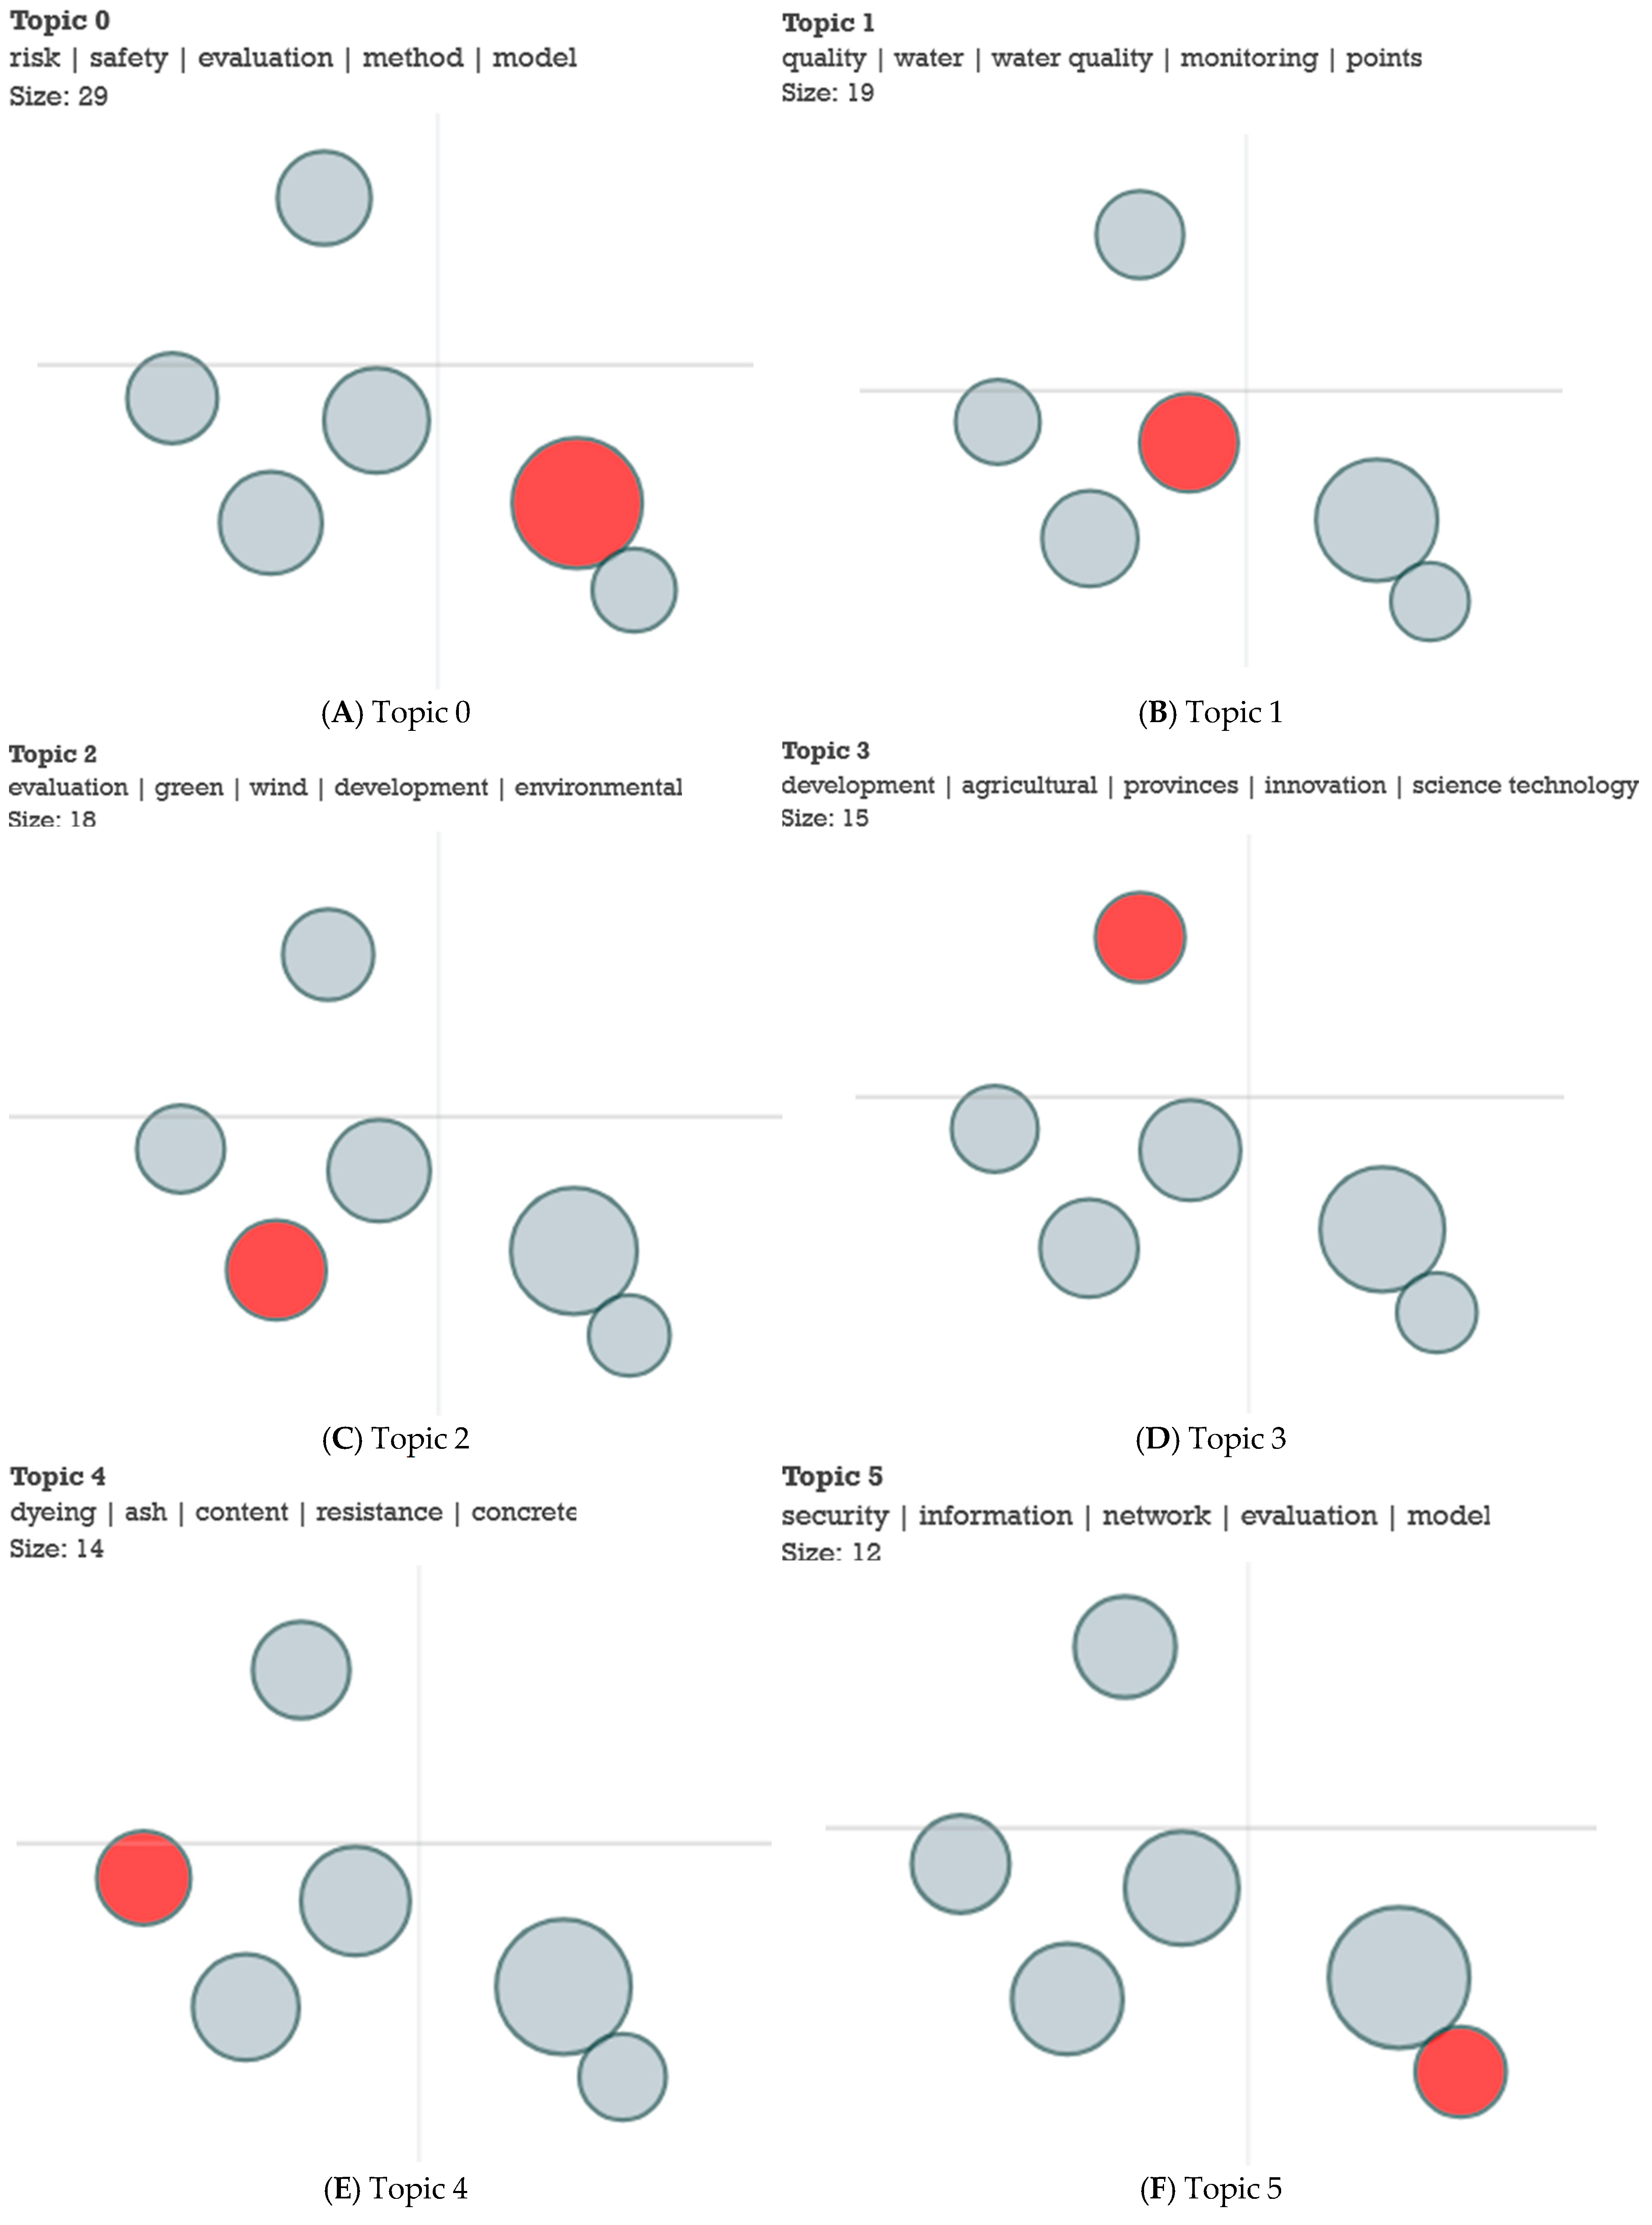
In terms of BERTopic analysis, six topics have been identified, noted from 0 to 5, as depicted in Figure 23 through grey circles.
Furthermore, for each topic, the top-10 most-used keywords have been extracted and discussed in the following, while in Figure 24, the top 5 of these keywords are highlighted. In this figure, each topic one is referring too is highlighted in red circles, while the remainder of the topics are depicted in grey circles.
BERTopic achieved a coherence score of 0.423, which is within the expected range for transformer-based topic models and notably higher than the best-performing LDA configuration (0.351). This indicates that BERTopic extracted more semantically coherent clusters of documents, despite the inherent noise and heterogeneity of bibliometric abstracts.
BERTopic 0 captures the core methodological foundation of grey clustering, with strong links to risk management, safety evaluation, and decision models, featuring keywords such as risk, safety, evaluation, method, model, grey, management, quality, and study. Environmental monitoring, especially water and air quality assessments using grey clustering research, is encompassed within BERTopic 1 through the extracted keywords such as quality, water, water quality, monitoring, points, river, method, air, air quality, and results.
Research topics associated with sustainable development and green energy applications, including wind power, construction, and industrial projects, are highlighted within BERTopic 2, as suggested by the extracted keywords, such as evaluation, green, wind, development, environmental, model, industry, construction, power, and project.
Furthermore, grey clustering used in agricultural development, science and technology evaluation, and regional policy studies can be observed within BERTopic 3, characterised by keywords such as development, agricultural, provinces, innovation, science technology, technology, science, and agricultural science. A focus on materials science and industrial processes, including textile dyeing, construction materials, and medicinal material analysis, can be observed through the keywords associated with BERTopic 4—namely dyeing, ash, content, resistance, concrete, materials, medicinal, and fabrics. Last, BERTopic 5 focuses on information and network security, with grey clustering applied to computer systems, trusted networks, and IT evaluation models, research focus highlighted through the keywords security, information, network, evaluation, computer, trust, information security, and computer network.
Thus, the topics featuring grey clustering according to the BERTopic analysis are as follows: BERTopic 0, Grey Clustering for Risk and Safety Evaluation Frameworks; BERTopic 1, Environmental Monitoring: Water and Air Quality Assessment; BERTopic 2, Sustainable Development and Green Energy Projects; BERTopic 3, Agricultural Development and Technological Innovation; BERTopic 4, Materials Science and Industrial Processes; and BERTopic 5, Information and Network Security.
Considering the results obtained through LDA, BERTopic, and thematic maps provided above, the intersection of the identified topics is further discussed in the following.
First, a strong overlap is observed within LDA Topic 1 and BERTopic 0, as well as between LDA Topic 2 and BERTopic 1, as depicted in Table 6. As an observation, it can be noted that the overlap highlighted in Table 6 is obtained between LDA topics that retained 54.1%, respectively, 14.2% of tokens, and large BERTopics as depicted in Figure 24, as both of them supported themes identified in the thematic map in Figure 10 as basic themes. As a result, the importance of these two research directions is highly pointed out by the three considered analyses, namely LDA, BERTopic, and thematic maps.
As for the remainder of the topics identified through LDA and BERTopic, it has been observed that three of them provide a partial overlap, as depicted in Table 7.
Specifically, LDA Topic 3 overlaps with BERTopic 2 on issues related to grey clustering used for project or sustainability evaluation. This overlap is also identified within a cluster in the motor themes quadrant of the thematic map in Figure 10.
Furthermore, LDA Topic 4 and BERTopic 5 overlap on issues related to safety and risk evaluation. This research direction related to grey clustering can also be observed in the clusters formed within the thematic map in the area dedicated to niche themes. The positioning within the quadrant dedicated to niche themes might be due to the fact that the number of works associated with this research area is reduced, as observed by the reduced percentage of tokens associated with LDA Topic 4.
The last partial overlap is between LDA Topic 5 and BERTopic 4 on issues related to grey clustering in industrial and material applications. The clusters formed within the thematic map further highlight this research direction through the words included in the emerging/declining themes quadrant.
Besides the themes identified above, the research interests in the area of grey clustering include directions as highlighted by LDA Topic 6 or BERTopic 3 or in the clusters depicted in the thematic map, among which one can mention areas such as agriculture, higher education, green energy, healthcare, disasters, etc.
Thus, based on the identified themes in Table 6 and Table 7, in the next section, the review will be conducted based on the consolidated topics.

4.5. Papers’ Review Based on Topics

As already demonstrated, the domain is constantly expanding due to the rapid advancement of technology. Especially in recent years (2020–2024), there has been observed in the scientific community the tendency of combining grey clustering with machine learning algorithms and artificial intelligence tools, which contribute to digital twin applications and real-time monitoring systems. These new developments are used especially in sustainability analytics, including environmental quality, ESG evaluation, and resource planning. The new decision frameworks (three-way decisions, multi-stage assessment models) increase the methodological opportunities and prove the contribution of grey clustering to the practical applications in the field.
In the following pages, some of the main domains in which grey clustering made a significant impact will be discussed.

4.5.1. Methodological Foundations and Frameworks for Risk and Safety Evaluation

Grey clustering has a substantial contribution in the risk and safety evaluation field, as it can integrate numerous risk factors and classify them into levels, prioritise tasks, guide planning, monitor safety performance, improve the accuracy of the evaluation, offer preventive measures, etc. Thus, the number of papers published around this topic in the scientific community further proves this remark.
Wu et al. [54] are oriented towards identifying the most efficient manner in which natural gas pipelines can be managed, and for this, they involved a multi-level grey clustering approach. The authors investigated key aspects, such as the amount of gas moved, the profit, and the safety of the pipeline. For testing the method’s efficiency, a case study from China was considered, where seven distinct operation plans for a pipeline were compared. It was demonstrated that the optimum plan is not influenced by a single factor, but by the overall performance.
Li et al. [55] wrote a paper about safety evaluation in industries, focusing especially on how to improve it. A new evaluation method based on improved grey clustering is proposed, which helped in identifying and classifying the safety indicators. Then, the grey analytic hierarchy process was involved for analysing the experts’ opinions and proposing efficient strategies. The framework was tested on a real Chinese aviation dataset, proving its efficiency in evaluating the safety of the organisation.
Qi et al. [56] conducted research about traffic safety and investigated which zones near the bus stops are the most dangerous. For collecting the traffic data, drones and video software were utilised. The risk levels were assessed with the help of a grey clustering model, based on which the places where accidents are more likely to happen were uncovered. A case study for Guangzhou was included, and the results proved that the highest risk is when the buses exit at the stop, and in terms of lanes, the ones that are near the bus stop involve frequent small accidents, while the ones placed at a distance do cause dangerous accidents, but fewer.
Chen et al. [57] were focused on the risks associated with construction sites, as traditional safety risk is based more on engineers’ experience than on real-time analyses and predictions. The authors involved a knowledge graph for evaluating incidents from the past, and a grey clustering method for identifying the risk and classifying them based on levels. The approach was tested, and it demonstrated its high efficiency in detecting unsafe and risky behaviours.
Lv et al. [58] wrote about large chemical plants and their associated accident risks. Various safety risk indicators were considered, and a multi-level risk assessment framework was proposed. Grey clustering helped in grouping the risks into levels, and then it was tested on a real Chinese ammonia plant, proving the method’s efficiency and power in assessing risks and improving safety.
Other papers published in this sector address topics related to risks of bird strikes at airports [59], traffic accidents [60], big commercial aircraft suppliers [61], freight transport [62], and the healthcare supply chain [63].
Of those mentioned, the grey clustering method has an important role in the risk and safety evaluation field, especially when it is combined with other techniques and types of analyses. The authorities’ involvement and collaboration with the scientific community are necessary for combating the current challenges, improving safety, and preventing risks.

4.5.2. Environmental Monitoring and Assessment

Various challenges are associated with the environment, including pollution, climate change, soil contamination, toxic materials’ waste, etc. The high interest in saving and protecting the environment has attracted the scientific community’s interest. The academics are continuously writing about this subject matter, exploring different techniques and methods, testing the results, and assisting authorities in decision-making processes.
Liu [64] is oriented towards reducing the pollution in outdoor landscape water. Initially, he monitored various essential indicators, and then used a grey clustering model to evaluate the quality. He tested the approach on different waters, and based on the results, a treatment plan was proposed. It was mentioned that after treatment, the quality of the water was significantly increased.
Yu et al. [65] were focused on testing the air quality in a region from northeastern China, namely the Bohai Coastal Region. The scientists proposed a new assessment method, which involves entropy weight for identifying the key factors, and fuzzy evaluation and grey clustering for examining pollution and grouping the factors that influence it into levels. To demonstrate the method’s efficiency, some numerical tests were included in the research.
Delgado et al. [66] discussed in their paper the impact of mining on water pollution levels in Peru. For evaluating the water quality in the rivers (Yauli and Andaychagua), the scientists utilised fuzzy logic and grey clustering. The results demonstrated that during wet seasons, the water quality drops, compared to dry seasons, when the quality is generally good.
Hu et al. [67] were focused on air quality in cities. They proposed a new evaluation index, which involved grey fixed weight clustering, and tested the method on 74 cities from China. For each city, the overall pollution level was measured and examined, the technique’s efficiency and the results’ accuracy being demonstrated.
In the manuscript belonging to Delgado et al. [68], the grey clustering method was used for evaluating the quality of sediments in rivers from Peru. The researchers established 23 monitoring points across the river, measured the heavy metals, and then compared the results with Canadian sediment quality standards. The findings showed that most of the sediments are safe and do not have a negative impact on the aquatic life. There were also some specific spots identified that required attention from the authorities.
Other papers published in the scientific literature discuss air quality in the COVID-19 pandemic context [69], surface water quality [70], and reservoir eutrophication [71].
Considering these, it is important for everyone to understand the importance of the environment, contribute to and engage in ecological protection, and be aware of the impact and consequences that arise from neglecting the environment. The authorities’ involvement in this sector is essential, as the need for resources is considerable. They must collaborate closely with the academic community and identify the most efficient ways and strategies in which existing challenges can be combated and future ones prevented.

4.5.3. Grey Clustering in Project/Sustainability Evaluation

During the last decade, an increased interest in sustainability evaluation was noticed. As the degree of pollution is constantly rising due to various factors, aspects such as social responsibility, environmentally friendly policies, and projects’ performance (e.g., quality, risks, etc.) have gained the academic community’s attention.
Lin et al. [72] wrote a paper related to Taiwan’s green spaces placed near buildings. Grey clustering and the analytic hierarchy process were used for identifying the key factors, assessing the eco-friendliness level, and splitting the green areas into levels. The approach demonstrated a high efficiency when working with very similar projects, which is useful for future strategies.
Chen et al. [73] were focused on improving buildings’ energy performance. They investigated the implementation of photovoltaic technology and evaluated the associated risks by using methods such as grey clustering, DEMATEL, and analytic network process. A Chinese case study was involved, and the results proved the model’s power in identifying risks and understanding the connection between them. The research is useful for all individuals interested in this topic, but especially for architects and engineers.
Tan et al. [74] developed a new model that takes into consideration the environmental and social factors in wind farm site evaluation, as the current Chinese approaches focus only on the economic aspects. The evaluation index system, weighting method, grey clustering, and ideal matter element technique were involved in the research. The factors were grouped with respect to their importance level, and wind farm sites were ranked, offering the possibility of identifying the best locations.
Li et al. [75] explored the environmental investments in a company named Haier, focusing on the period between 2007 and 2011. Through this paper, the authors wanted to highlight the connection between the amount spent on environmental protection in a company and its economic results. A grey clustering model was utilised for assessing various factors, and the results demonstrated that environmental investments had a significant impact on the company’s economic growth, reducing pollution and energy consumption.
Huo et al. [76] addressed in their paper the issue of old residential areas’ green renovation. The challenges associated with this initiative are substantial, thus necessitating the identification of optimal methods. The attention was oriented towards a project from a Chinese city (Chongqing). Once the list of risk factors was created, grey clustering analysis and C-OWA were used for evaluating and grouping the risks into relevant categories. The approach was considered efficient as it offered an overview of the renovation project’s risks and helped in reducing or even preventing some problems.
Other papers that involve grey clustering in project or sustainability evaluation are focused on smart industrial parks [77], green building [78], low-carbon sustainability in wind power projects [79], highways’ green construction in frozen season [80], and urban trend ecology [81].
Having all these mentioned, the power of grey clustering when applied in this sector is significant, as it assists authorities in better understanding the risks and classifying them in distinct levels/categories, identifying and prioritising key factors which influence sustainability or projects’ evolution, supporting decision-making processes, improving the strategies, and planning, optimising resources, and even preventing the occurrence of critical issues in the early stages.

4.5.4. Grey Clustering in Risk and Security Evaluation

Another field of high interest in the academic community is represented by risk and security evaluation. The power of grey clustering in the mentioned sector is significant; thus, the number of published articles related to this subject matter is also considerable.
The paper written by Tan et al. [82] is focused on social media platforms, more specifically on detecting existing rumours. The authors utilised three distinct datasets and combined deep learning algorithms with grey clustering for identifying the relevant comments from posts and predicting whether a post is a rumour or not. The results proved the method’s efficiency and its relevance in online risk evaluation.
Yu [83] focused on one popular challenge in today’s technological world, namely, computer network security. The scientist involved the analytic hierarchy process and the grey clustering method for identifying the most important factors that affect network security. Then, the factors were grouped into distinct categories with respect to risk levels.
Guo et al. [84] proposed a security evaluation model that aims to detect the challenges associated with edge computing and IoT, involving a grey clustering model for ranking the security levels. The results proved the technique’s high performance in both classifying and assessing the system’s security.
Li et al. [85] conducted a research paper, focused on a new performance analysis model designed to train specialists from Chinese colleges in information security. As the data is often unclear, incomplete, or unobjective, the authors involved grey clustering and fuzzy information transformation and demonstrated the approach’s performance when applied to real-world datasets.
Duan et al. [86] discussed trusted computing, a method that registered great efficiency in protecting information systems. The authors proposed a new dynamic technique that is based on the existing one, but it includes an extra step in which the security risk is evaluated, involving grey systems theory. It is demonstrated that the method’s efficiency is significantly faster and more accurate in detecting security issues, compared to the traditional method.
Other authors interested in grey clustering application in risk and security conducted various research related to the security of network information [87,88], e-commerce security [89], attack effects [90], and malicious nodes detection [91].
Having all these presented, the high contribution that grey clustering has on risk and security is evident. The power of handling incomplete data, identifying risk levels, improving decision-making processes, and detecting patterns are just some of the main benefits. This topic is very important, especially in the current technological world, which brings with it a multitude of consequences and challenges.

4.5.5. Grey Clustering in Industrial and Material Applications

Grey clustering method also has a significant impact on the industrial and material applications sector, as it can assess the quality of specific materials and classify them based on different factors, identify risks, predict the performance of some products, support decision-making, and handle incomplete data.
Shao et al. [92] investigated how basalt fibre length affects the concrete’s durability. The scientists utilised neural networks and grey clustering for identifying the connections between factors and making predictions. The findings of the study demonstrated that the strength and durability of the concrete are directly influenced by the fibre length.
García et al. [93] published a paper about tanning paiche fish skins and explored its impact on the environment. The authors used grey clustering and compared three tanning methods: traditional chrome tanning, chrome-free tanning, and optimised chrome-free tanning. The results showed that the last approach was the best one in terms of environmental performance, while the traditional one was the worst.
Sharma and Vyas [94] analysed the possibility of replacing river sand with pond ash in the composition of cement mortar. The authors tried different combinations of percentages, and with the grey clustering method’s help, found that 60% pond ash and 40% river sand was the best one, in terms of price, strength, and eco-friendliness.
Wang et al. [95] focused on the issue associated with traditional denim dyeing, as the overall process affects the environment, due to the increased level of chemicals, water, and energy used. Grey clustering was utilised for analysing and assessing the dying process. The authors examined the power of nitrogen gas, proving that it maintained the stability of the dyeing process, improved the colour quality (more than 50%), and was greener and more efficient when compared to the traditional approach.
Zhang et al. [96] analysed the impact of a new fibre, namely Hollow Coffee Carbon Polyester (HCCP), when mixed with cotton for various fabric types. The scientists considered distinct amounts for each fabric, and with the grey clustering method’s assistance, compared and assessed each one of them, focusing on key factors (strength, comfort, antibacterial properties). The results demonstrated that HCCP fibre has a positive impact on the fibre (the higher the HCCP, the stronger, warmer, and cleaner the fibre), although it decreases the pilling resistance.
Other papers linked to this domain address topics such as radiation protection fabrics [97], electromagnetic shielding [98], seaport buildings [99], geopolymer concrete made of fly ash [100], and authentic medicinal materials [101].
As observed above, the importance of grey clustering in the field is substantial. The studies offered by the scientific community may represent crucial details for authorities and people involved in different industries, as they can guide and assist in improving the quality of the processes, optimising production, promoting sustainability, and guiding manufacturers.

5. Limitations

The aim of this section is to discuss in an objective manner the present study’s limitations, aspects that may offer an in-depth overview of the approach followed by the authors, and can also contribute to future directives of this research.
Through this manuscript, it was intended to analyse the publications related to grey clustering methods and applications. Thus, 318 English-written articles, published between 1989 and 2024, were selected from the Web of Science database.
The first limitation that should be highlighted is associated with database dependence bias, as only the Web of Science Core Collection was used. As mentioned, for this article, we opted for a single-source approach, so the data collection set was collected exclusively from the Web of Science database. This decision was based on multiple arguments, among which are the database’s popularity and recognition within academic community, ease of integration with scientometric tools (Biblioshiny, VOSviewer, and CiteSpace), user-friendly and intuitive interface, up-to-date version, huge collection of works from all over the world across various domains, individual analyses’ challenges associated with data collected from multiple sources, etc. For this research, the above approach was regarded as the most suitable, but even under these circumstances, the significance of other sources, such as Scopus or IEEE, is not disregarded. As for future research directives, interested scientists are encouraged to explore ways to integrate multiple sources without introducing challenges during the analysis phase.
Moreover, when collecting the dataset, several filter criteria were applied with the intention of excluding all papers that were not suitable for this investigation or not related to grey clustering methods and applications.
The key search took into consideration both types of spellings, “grey cluster*” and “gray cluster*”, while the use of * at the end of the root term ensured the retrieval of all types of combinations generated from the root term. This might represent a limitation, as there is a possibility of omitting some relevant papers due to inconsistencies in terminology.
Despite our filtering, a language bias persists. Thus, another limitation consists of the language restriction, as all studies that were not conducted in English were excluded. Even though this criterion had a small impact on the dataset, among the few works omitted, some important contributions might have been present.
Document type was a criterion that had a significant impact on the dataset and reduced it by almost half. Only the contributions marked as “article” in WoS were included in the examination; thus, important research findings from other types of documents might have been neglected.
Then, the following restriction was about removing the papers published in the current year (2025), which were considered incomplete from a scientific point of view. The execution of this query did not significantly alter the set of dates, but among the excluded articles, some might have been important for the research.
The last limitation that should be outlined here refers to subjectivity in PRISMA screening. Therefore, it has been observed that five articles were outside the research field as they were covering other topics, not related to the “grey cluster” from the grey systems theory. Given the human involvement in the filtering process, minor mistakes/errors may have occurred.
Nevertheless, in terms of analyses performed within the paper, it should be mentioned that topic modelling results should be interpreted with caution due to the limitations of LDA and BERTopic in relatively small corpora. LDA tends to over-fragment themes or merge semantically distinct topics when the text corpus is limited in size or the terminology is not standardised. BERTopic, while more semantically sensitive, may produce unstable clusters when working with short abstracts or sparse domain-specific vocabulary. In order to address such a limitation, a discussion has been put forward related to the overlapping of the clusters obtained through BERTopic, LDA and Biblioshiny in Section 4.
Based on the provided discussion, it should be acknowledged that the discrepancies between the multiple approaches used, namely BERTopic, LDA and Biblioshiny topic modelling, reflect methodological differences and field fragmentation. Thus, it can be observed that co-occurrence-based methods tend to emphasise dominant, frequently repeated terminology, whereas topic models (especially BERTopic) highlight finer-grained thematic niches that are semantically coherent but less frequently labelled using shared keywords. The combination of these methods, therefore, provides a more complete representation of the field: Biblioshiny identifies broad thematic domains, LDA uncovers stable latent topics, and BERTopic reveals emerging or specialised subfields.
As a result of the topic and themes analysis, it can be noted that the thematic structure of grey clustering research comprises four stable domains—environmental assessment, risk and performance evaluation, sustainability and urban development, and decision-making frameworks. On the other hand, specialised application niches emerge more clearly in embedding-based models than in co-occurrence networks, indicating that the field is simultaneously expanding and fragmenting. Thus, it can be said that the discrepancies across clustering approaches in various methods used are signals of a heterogeneous, rapidly evolving research landscape, rather than errors in identifying themes and topics.
Considering all the above-mentioned limitations, future researchers interested in further expanding the domain are encouraged to address them and find better alternatives for obtaining larger datasets, collected from multiple sources, and apply filters only when it is strictly necessary.

6. Conclusions

Having discussed everything in the previous chapters, the present section is oriented towards highlighting the main findings and final remarks.
This manuscript offered an overview of the scientific literature about grey clustering methods and applications, including 318 English-written articles, published within a period of 36 years (1989–2024). The papers were collected exclusively from the Web of Science database and were carefully filtered considering various factors (keywords—“grey_cluster*” and “gray_cluster*”, language—English, type of document—article, year of publication—between 1989 and 2024, manual selection), before the actual investigation. Once the dataset was collected, a comprehensive bibliometric investigation was performed, including components specific to review research and topic modelling approaches.
The idea behind the new approach followed in this manuscript is based on the fact that bibliometric results can complement qualitative synthesis and offer a stronger overview of the domain. Thus, investigations such as thematic maps and co-occurrence networks uncovered core research topics, trends, clusters, areas of high interest, and research directions that then served as the foundation of the qualitative review. It was noticed that some of the key themes and gaps identified in the bibliometric investigation phase were further addressed in some of the reviewed papers, which further demonstrates the dependency between the two stages.
Furthermore, in terms of topic analysis, it has been observed that in the scientific literature, this approach is more and more used in recent studies along with the bibliometric analysis for providing more insight on the papers written on various research topics, by combining the bibliometric approach with either LDA [102] or BERTopic [103], which supported the decision to use this approach also in the present paper.
The following paragraphs will provide the answers to the initial questions raised in the introduction.
In terms of early distribution of the studies associated with grey clustering, an upward trend was noticed, marked by small fluctuations. In the first part of the interval (1989–2001), the scientific production in this field was extremely low—a maximum of one publication per year. Then, the field started to gain the scientists’ attention and reached 37 articles in 2022. The scientific annual growth rate registered for the research field is 10.78%, proving the importance of the domain and the power of grey clustering in identifying, classifying, and preventing risks in any sector.
According to the review performed for the top-10 most-cited documents, some details were uncovered. The themes addressed by the academics are varied and cover distinct areas and domains, proving once again the extensive applicability of grey clustering. The themes addressed in the papers from the hierarchy are mainly related to environment, sustainability, green practices, industry and engineering applications, decision-making and risk analysis. The data from the studies was collected from various sources, including interviews, real datasets, and experts’ evaluations. It was also noticed in these manuscripts an increased interest in the case studies related to China, India, and even Peru.
Furthermore, the thematic evolution uncovered the key themes addressed and their evolution over time. It was observed that scientists combined grey clustering with other methods (e.g., analytic hierarchy, evaluation models, artificial intelligence, etc.) for improving the quality of the analyses and the accuracy of the results. As already mentioned, the themes are diverse due to the high power of grey clustering in any sector, and cover topics such as environmental monitoring, air and water quality, resource management, public health, sustainability, traffic accidents, and climate change. Despite the diversity of the subjects and their evolution with respect to the world’s needs, the studies have similar purposes: identifying and assessing the risks, working with large and unclear data, evaluating the performance, prioritising tasks, better managing the resources, contributing to decision-making process, improving the quality, combating current challenges, finding optimal and green alternatives, and preventing issues in early stages.
Going further with the discussion, in this paper, Latent Dirichlet Allocation (LDA) and BERTopic analyses were also conducted.
According to LDA, six key topics were uncovered: grey clustering for performance evaluation and decision-making frameworks; grey clustering in environmental and water quality assessment; grey clustering in expert systems and project evaluation; grey clustering for risk assessment and socio-technical systems; grey clustering in healthcare, industrial processes, and disaster impact evaluation; and grey clustering for multi-criteria decision-making in engineering and environment.
Similarly, based on the BERTopic analysis, six main themes were identified: grey clustering for risk and safety evaluation frameworks; environmental monitoring: water and air quality assessment; sustainable development and green energy projects; agricultural development; materials science and industrial processes; and information and network security.
Considering all these, the present manuscript aims to provide support for authorities and individuals interested in grey clustering. Based on the comprehensive review performed in the paper, and with the assistance of different analyses, the significant contribution of grey clustering in any domain was noticed. The power of grey clustering in identifying and evaluating risks, improving the overall processes through informed decision-making, guiding planning, and preventing issues is proven by each article found in the dataset. Its wide applicability in various sectors, including environment, sustainability, engineering, construction, and healthcare, demonstrates the methods’ efficiency.
As the field is under continuous research, there are also challenges and areas that require future investigation and resources, such as gathering high-dimensional datasets from the real world, integrating models with decision-making tools and other techniques, choosing the key parameters, handling dynamic systems, time-consuming computations, etc. Grey clustering has the power to combat the current challenges and risks, and at the same time protect the environment. The involvement of authorities and their close collaboration with the academic community is of high importance, especially for domains with high-level risks.

Supplementary Materials

The following supporting information can be downloaded at: https://www.mdpi.com/article/10.3390/math13244040/s1, Table S1: PRISMA 2020 Checklist.

Author Contributions

Conceptualisation, C.D., G.D., A.S. and M.P.; methodology, A.S., G.D. and C.D.; software, G.D. and A.S.; validation, G.D., M.P. and C.D.; formal analysis, G.D., A.S. and M.P.; investigation, A.S., G.D. and C.D.; resources, C.D. and M.P.; data curation, G.D., A.S. and M.P.; writing—original draft preparation, G.D., A.S. and M.P.; writing—review and editing, C.D. and A.S.; visualisation, G.D., A.S. and C.D.; supervision, C.D.; project administration, C.D.; funding acquisition, C.D. All authors have read and agreed to the published version of the manuscript.

Funding

The work is supported by a grant from the Romanian Ministry of Research, Innovation and Digitalisation, project CF 178/31.07.2023—‘JobKG—A Knowledge Graph of the Romanian Job Market based on Natural Language Processing’.

Data Availability Statement

The original contributions presented in this study are included in the article.

Conflicts of Interest

The authors declare no conflicts of interest.

Appendix A. Description of the PRISMA Steps

  • Identification
As for the first stage, in the WoS database, three distinct queries were run. The first two consisted of retrieving all papers that contain one of the grey systems specific keywords in either titles, abstracts, or the keywords section. The search was conducted considering both types of spellings, “grey cluster*” (566 documents) and “gray cluster*” (148 documents). The use of * at the end of the root term ensured the retrieval of all types of combinations generated from the root term. The third one intersected the two previous results and returned 671 papers.
The keywords’ selection was an important step to which significant attention was given. The filtering based on multiple terms would have introduced unnecessary limitations; thus, the intention was to select all relevant papers about grey clustering and obtain an accurate dataset. This approach was also noticed in the case of other studies published in the scientific literature, which included in their keywords’ search both “grey_cluster*” and “gray_cluster*” terms and addressed topics in the same field: grey systems across uncertain environments [104], grey systems in sustainable digitalisation [10], grey systems contribution in decision-making domain under uncertainty [8], and grey systems theory in general [4].
  • Screening
Only the articles indexed in the WoS database, written in English, which addressed a topic related to grey clustering were selected. On the other hand, all non-English contributions, not marked as “articles”, retracted, or not related to the domain of interest, were excluded. The entire screening process is explained in the following paragraphs.
Initially, all papers written in languages other than English were excluded. This restriction had a minimal impact and reduced the dataset by nine papers, proving that English is a global academic language. This filter was also observed in other bibliometric research [105,106,107,108].
The following criterion consists of eliminating all the papers that are not marked as “articles” in WoS. Conference proceedings were not excluded as they also belong to this category [109], and interested readers can also refer to the paper written by Donner et al. [110], which highlights the connection between papers’ classifications and citations. This filter had a substantial impact, reducing the dataset by almost half (324 papers).
Then, the next restriction was about removing all articles published in 2025. The current year is considered incomplete, given that additional papers are expected to be published until its end, a fact which may affect the results of the present investigation. After executing this query, the dataset decreased by eight papers.
After all these exploratory steps, a manual selection was performed. This extra check ensured that the selection of articles was consistent and unbiased.
Therefore, seven retracted articles were excluded from the utilised scientometric tools (Biblioshiny, VOSviewer, and CiteSpace) once the raw file was imported.
  • Eligibility
In the third stage of the PRISMA flowchart, the records were screened for relevance and duplication. After a close investigation of the titles and abstracts of the remainder 323 papers, it has been observed that five articles were outside the research field considered as they were dealing with the calcium-binding EF-hand proteins and the structural/functional significance of conserved regions within them, specifically the so-called “black” and “gray” clusters (highly conserved amino acid residues important for stability, folding, or function). Even though the term “gray cluster” could have been found within the five papers, it was not referring to the “grey cluster” from the grey systems theory.
  • Included
As a result, the number of articles retained in the analysis is 318 papers. For each manuscript, details related to document type, language, authors, title, journal, keywords, abstract, references, etc., were retrieved. All these details contributed to a comprehensive examination of the field.

References

  1. Deng, J.-L. Control Problems of Grey Systems. Syst. Control Lett. 1982, 1, 288–294. [Google Scholar] [CrossRef] [Scilit]
  2. Hu, M.; Liu, W. Grey System Theory in Sustainable Development Research—A Literature Review (2011–2021). Grey Syst. Theory Appl. 2022, 12, 785–803. [Google Scholar] [CrossRef] [Scilit]
  3. Pan, W.; Jian, L.; Liu, T. Grey System Theory Trends from 1991 to 2018: A Bibliometric Analysis and Visualization. Scientometrics 2019, 121, 1407–1434. [Google Scholar] [CrossRef] [Scilit]
  4. Yang, Y.; Xie, N.; Liu, B.; Liu, C. A Bibliometric Analysis on Grey System Theory and Its Application in 1982–2021. J. Grey Syst. 2022, 34, 66. [Google Scholar]
  5. Delcea, C. Grey Systems Theory in Economics—A Historical Applications Review. Grey Syst. Theory Appl. 2015, 5, 263–276. [Google Scholar] [CrossRef] [Scilit]
  6. Tao, L.; Ailin, L.; Xie, N.; Liu, S. Grey System Theory in Engineering: A Bibliometrics and Visualization Analysis. Grey Syst. Theory Appl. 2022, 12, 723–743. [Google Scholar] [CrossRef] [Scilit]
  7. Jiang, P.; Dong, Z.; Sun, H.; Song, Y.; Zou, Q. Grey System Theory in Supply Chain: Emerging Hotspots and Trends. Grey Syst. Theory Appl. 2025, 15, 124–144. [Google Scholar] [CrossRef] [Scilit]
  8. Sandu, A.; Diaconu, P.; Delcea, C.; Domenteanu, A. Emphasizing Grey Systems Contribution to Decision-Making Field Under Uncertainty: A Global Bibliometric Exploration. Mathematics 2025, 13, 1278. [Google Scholar] [CrossRef] [Scilit]
  9. Delcea, C.; Cotfas, L.-A. Supplier Selection Using Grey Systems Theory. In Advancements of Grey Systems Theory in Economics and Social Sciences; Delcea, C., Cotfas, L.-A., Eds.; Springer Nature: Singapore, 2023; pp. 85–138. ISBN 978-981-19993-2-1. [Google Scholar]
  10. Crișan, G.-A.; Domenteanu, A.; Popescu, M.E.; Delcea, C. Decision-Making for Sustainable Digitalization Through Grey Systems Theory: A Bibliometric Overview. Sustainability 2025, 17, 4615. [Google Scholar] [CrossRef] [Scilit]
  11. Mukherjee, S.; Kar, S. Application of Fuzzy Mathematics and Grey Systems in Education. J. King Saud Univ. Comput. Inf. Sci. 2012, 24, 157–163. [Google Scholar] [CrossRef] [Scilit]
  12. Pham, C.; Nguyen, P.; Thanh Phan, P. Application of the Grey System Theory in Construction Management. Eng. Technol. Appl. Sci. Res. 2022, 12, 9087–9091. [Google Scholar] [CrossRef] [Scilit]
  13. Peng, X.; Li, X.; Yang, X. Analysis of Circular Economy of E-Commerce Market Based on Grey Model under the Background of Big Data. J. Enterp. Inf. Manag. 2021, 35, 1148–1167. [Google Scholar] [CrossRef] [Scilit]
  14. Majchrzak, J.; Więcek-Janka, E. Application of Grey Systems Theory in the Analysis of Relationships between Family Enterprise Communication and Their Market Attitude. Inform. Ekon. 2020, 2019, 30–48. [Google Scholar] [CrossRef] [Scilit]
  15. Kumar, V.; Chhabra, J.K.; Kumar, D. Grey Wolf Algorithm-Based Clustering Technique. J. Intell. Syst. 2017, 26, 153–168. [Google Scholar] [CrossRef] [Scilit]
  16. Liu, H.; Chen, R.; Cao, S.; Lv, H. Evaluation of College English Teaching Quality Based on Grey Clustering Analysis. Int. J. Emerg. Technol. Learn. 2021, 16, 173. [Google Scholar] [CrossRef] [Scilit]
  17. Delgado, A.; Condori, R.; Hernández, M.; Lee Huamani, E.; Andrade-Arenas, L. Artificial Intelligence Model Based on Grey Clustering to Access Quality of Industrial Hygiene: A Case Study in Peru. Computation 2023, 11, 51. [Google Scholar] [CrossRef] [Scilit]
  18. Karimi, T.; Ahmadian, M. Grey Clustering and Grey Ranking of Bank Branches Based on Grey Efficiency. Grey Syst. Theory Appl. 2023, 14, 1–20. [Google Scholar] [CrossRef] [Scilit]
  19. Liang, Y.; Zhang, L.; Lu, H. Growth Analysis of New-Energy Enterprises in China: A Grey Possibility Degree Clustering Model for Panel Data. Data Sci. Informetr. 2024, 4, 21–31. [Google Scholar] [CrossRef] [Scilit]
  20. Ţilică, E.V.; Dragotă, V.; Delcea, C.; Tătaru, R.I. Portfolio Management under Capital Market Frictions: A Grey Clustering Approach. Financ. Innov. 2024, 10, 110. [Google Scholar] [CrossRef] [Scilit]
  21. Delcea, C.; Cotfas, L.-A.; Mierzwiak, R.; Ioanas, C. Grey Clustering of the Variations in Reverse Pyramid Boarding Method Considering Pandemic Restrictions. J. Grey Syst. 2022, 34, 53. [Google Scholar]
  22. Delcea, C.; Profiroiu, C.M.; Profiroiu, A.G.; Raluca Cibu, B.; Nica, I.; Cotfas, L.-A. Complex Decision Making in Counties Socio-Economic and Security Contexts through Grey Clustering. J. Grey Syst. 2025, 37, 115. [Google Scholar]
  23. Xie, N.; Su, B.; Chen, N. Construction Mechanism of Whitenization Weight Function and Its Application in Grey Clustering Evaluation. J. Syst. Eng. Electron. 2019, 30, 121. [Google Scholar] [CrossRef] [Scilit]
  24. Hu, C.-Z.; Xie, N.-M.; Yin, S.-M. Civil Aircraft Cost Drive Parameters Selecting Method Based on Grey Clustering Model. In Proceedings of the 2015 IEEE International Conference on Systems, Man, and Cybernetics, Kowloon, Hong Kong, 9–12 October 2015; IEEE: Piscataway, NJ, USA; pp. 635–640. [Google Scholar]
  25. Liu, S.; Yang, Y.; Forrest, J.Y.-L. Grey Clustering Evaluation Models. In Grey Systems Analysis; Series on Grey System; Springer Nature: Singapore, 2022; pp. 125–151. ISBN 978-981-19-6159-5. [Google Scholar]
  26. Web of Science. 2024. Available online: www.webofknowledge.com (accessed on 13 July 2025).
  27. Ravšelj, D.; Umek, L.; Todorovski, L.; Aristovnik, A. A Review of Digital Era Governance Research in the First Two Decades: A Bibliometric Study. Future Internet 2022, 14, 126. [Google Scholar] [CrossRef] [Scilit]
  28. Cobo, M.J.; Martínez, M.A.; Gutiérrez-Salcedo, M.; Fujita, H.; Herrera-Viedma, E. 25 Years at Knowledge-Based Systems: A Bibliometric Analysis. Knowl. Based Syst. 2015, 80, 3–13. [Google Scholar] [CrossRef] [Scilit]
  29. Bakır, M.; Özdemir, E.; Akan, Ş.; Atalık, Ö. A Bibliometric Analysis of Airport Service Quality. J. Air Transp. Manag. 2022, 104, 102273. [Google Scholar] [CrossRef] [Scilit]
  30. Liu, W. The Data Source of This Study Is Web of Science Core Collection? Not Enough. Scientometrics 2019, 121, 1815–1824. [Google Scholar] [CrossRef] [Scilit]
  31. Liu, F. Retrieval Strategy and Possible Explanations for the Abnormal Growth of Research Publications: Re-Evaluating a Bibliometric Analysis of Climate Change. Scientometrics 2022, 128, 853–859. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  32. Page, M.J.; McKenzie, J.E.; Bossuyt, P.M.; Boutron, I.; Hoffmann, T.C.; Mulrow, C.D.; Shamseer, L.; Tetzlaff, J.M.; Akl, E.A.; Brennan, S.E.; et al. The PRISMA 2020 Statement: An Updated Guideline for Reporting Systematic Reviews. BMJ 2021, 372, n71. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  33. KeyWords Plus Generation, Creation, and Changes. Available online: https://support.clarivate.com/ScientificandAcademicResearch/s/article/KeyWords-Plus-generation-creation-and-changes?language=en_US (accessed on 1 November 2024).
  34. Delcea, C.; Oprea, S.-V.; Dima, A.M.; Domenteanu, A.; Bara, A.; Cotfas, L.-A. Energy Communities: Insights from Scientific Publications. Oeconomia Copernic. 2024, 15, 1101–1155. [Google Scholar] [CrossRef] [Scilit]
  35. Aria, M.; Cuccurullo, C. Bibliometrix: An R-Tool for Comprehensive Science Mapping Analysis. J. Informetr. 2017, 11, 959–975. [Google Scholar] [CrossRef] [Scilit]
  36. Întorsureanu, I.; Oprea, S.-V.; Bâra, A.; Vespan, D. Generative AI in Education: Perspectives Through an Academic Lens. Electronics 2025, 14, 1053. [Google Scholar] [CrossRef] [Scilit]
  37. Řehůřek, R.; Sojka, P. Software Framework for Topic Modelling with Large Corpora. In Proceedings of the LREC 2010 Workshop on New Challenges for NLP Frameworks, Valletta, Malta, 22 May 2010. [Google Scholar] [CrossRef] [Scilit]
  38. Grootendorst, M. BERTopic: Neural Topic Modeling with a Class-Based TF-IDF Procedure 2022. arXiv 2022, arXiv:2203.05794. [Google Scholar]
  39. Delgado, A.; Romero, I. Environmental Conflict Analysis Using an Integrated Grey Clustering and Entropy-Weight Method: A Case Study of a Mining Project in Peru. Environ. Model. Softw. 2016, 77, 108–121. [Google Scholar] [CrossRef] [Scilit]
  40. Jiskani, I.M.; Cai, Q.; Zhou, W.; Ali Shah, S.A. Green and Climate-Smart Mining: A Framework to Analyze Open-Pit Mines for Cleaner Mineral Production. Resour. Policy 2021, 71, 102007. [Google Scholar] [CrossRef] [Scilit]
  41. Sahoo, S.; Dhar, A.; Kar, A. Environmental Vulnerability Assessment Using Grey Analytic Hierarchy Process Based Model. Environ. Impact Assess. Rev. 2016, 56, 145–154. [Google Scholar] [CrossRef] [Scilit]
  42. Lu, Y.; Xu, Y.; Huang, J.; Wei, J.; Herrera-Viedma, E. Social Network Clustering and Consensus-Based Distrust Behaviors Management for Large-Scale Group Decision-Making with Incomplete Hesitant Fuzzy Preference Relations. Appl. Soft Comput. 2022, 117, 108373. [Google Scholar] [CrossRef] [Scilit]
  43. Lin, C.-H.; Wu, C.-H.; Huang, P.-Z. Grey Clustering Analysis for Incipient Fault Diagnosis in Oil-Immersed Transformers. Expert Syst. Appl. 2009, 36, 1371–1379. [Google Scholar] [CrossRef] [Scilit]
  44. Ke, X.; Wang, X.; Guo, H.; Yang, C.; Zhou, Q.; Mougharbel, A. Urban Ecological Security Evaluation and Spatial Correlation Research—Based on Data Analysis of 16 Cities in Hubei Province of China. J. Clean. Prod. 2021, 311, 127613. [Google Scholar] [CrossRef] [Scilit]
  45. Tsai, H.-C.; Hsiao, S.-W.; Hung, F.-K. An Image Evaluation Approach for Parameter-Based Product Form and Color Design. Comput.-Aided Des. 2006, 38, 157–171. [Google Scholar] [CrossRef] [Scilit]
  46. Rajesh, R. Measuring the Barriers to Resilience in Manufacturing Supply Chains Using Grey Clustering and VIKOR Approaches. Measurement 2018, 126, 259–273. [Google Scholar] [CrossRef] [Scilit]
  47. Li, Z.-T.; Yuan, M.-J.; Hu, M.-M.; Wang, Y.-F.; Xia, B.-C. Evaluation of Ecological Security and Influencing Factors Analysis Based on Robustness Analysis and the BP-DEMALTE Model: A Case Study of the Pearl River Delta Urban Agglomeration. Ecol. Indic. 2019, 101, 595–602. [Google Scholar] [CrossRef] [Scilit]
  48. Zhu, J.; Zhang, S.; Chen, Y.; Zhang, L. A Hierarchical Clustering Approach Based on Three-Dimensional Gray Relational Analysis for Clustering a Large Group of Decision Makers with Double Information. Group Decis. Negot. 2016, 25, 325–354. [Google Scholar] [CrossRef] [Scilit]
  49. Cotfas, L.-A.; Sandu, A.; Delcea, C.; Diaconu, P.; Frăsineanu, C.; Stănescu, A. From Transformers to ChatGPT: An Analysis of Large Language Models Research. IEEE Access 2025, 13, 146889–146931. [Google Scholar] [CrossRef] [Scilit]
  50. Cibu, B.-R.; Crăciun, L.; Molănescu, A.G.; Cotfas, L.-A. Exploring the Educational Applications of Large Language Models: A Systematic Review and Topic Analysis. Electronics 2025, 14, 4683. [Google Scholar] [CrossRef] [Scilit]
  51. Sandu, A.; Cotfas, L.-A.; Ioanăș, C.; Cișmașu, I.-D.; Delcea, C. E-Commerce Meets Emerging Technologies: An Overview of Research Characteristics, Themes, and Trends. J. Theor. Appl. Electron. Commer. Res. 2025, 20, 320. [Google Scholar] [CrossRef] [Scilit]
  52. Chuang, J.; Manning, C.D.; Heer, J. Termite: Visualization techniques for assessing textual topic models. In Proceedings of the International Working Conference on Advanced Visual Interfaces, Capri Island, Italy, 21–25 May 2012; pp. 74–77. [Google Scholar]
  53. Sievert, C.; Shirley, K. LDAvis: A method for visualizing and interpreting topics. In Proceedings of the Workshop on Interactive Language Learning, Visualization, and Interfaces, Baltimore, MA, USA, 27 June 2014; pp. 63–70. [Google Scholar]
  54. Wu, X.; Jia, W.; Li, Z. Synthetic Evaluation of Natural Gas Pipeline Operation Schemes Based on the Multi-Level Grey Cluster Decision Method. Arab. J. Sci. Eng. 2019, 44, 6045–6056. [Google Scholar] [CrossRef] [Scilit]
  55. Li, C.; Chen, K.; Xiang, X. An Integrated Framework for Effective Safety Management Evaluation: Application of an Improved Grey Clustering Measurement. Expert Syst. Appl. 2015, 42, 5541–5553. [Google Scholar] [CrossRef] [Scilit]
  56. Qi, W.; Ruan, L.; Zhi, Y.; Shen, B. Risk Area Identification Model of Bus Bay Stops Based on Distribution of Conflicts. Discret. Dyn. Nat. Soc. 2021, 2021, 9663966. [Google Scholar] [CrossRef] [Scilit]
  57. Chen, Q.; Long, D.; Yang, C.; Xu, H. Knowledge Graph Improved Dynamic Risk Analysis Method for Behavior-Based Safety Management on a Construction Site. J. Manag. Eng. 2023, 39, 04023023. [Google Scholar] [CrossRef] [Scilit]
  58. Lv, C.; Wu, Z.; Liu, Z.; Shi, L. The Multi-Level Comprehensive Safety Evaluation for Chemical Production Instalment Based on the Method That Combines Grey-Clustering and EAHP. Int. J. Disaster Risk Reduct. 2017, 21, 243–250. [Google Scholar] [CrossRef] [Scilit]
  59. Wang, J.; Ning, H.; Chen, W.; Li, J.; Wan, J.; He, W. Airport Bird-Strike Risk Assessment Model with Grey Clustering Evaluation Method. Chin. J. Electron. 2012, 21, 409–413. [Google Scholar]
  60. Hu, L.; Bao, X.; Wu, H.; Wu, W. A Study on Correlation of Traffic Accident Tendency with Driver Characters Using In-Depth Traffic Accident Data. J. Adv. Transp. 2020, 2020, 9084245. [Google Scholar] [CrossRef] [Scilit]
  61. Liu, S.; Zhang, S.; Jian, L.; Yuan, W.; Yang, Y. Performance Evaluation of Large Commercial Aircraft Vendors. J. Grey Syst. 2015, 27, 1–11. [Google Scholar]
  62. Kumar, A. Transition Management Theory-Based Policy Framework for Analyzing Environmentally Responsible Freight Transport Practices. J. Clean. Prod. 2021, 294, 126209. [Google Scholar] [CrossRef] [Scilit]
  63. Hossain, M.; Thakur, V.; Kazançoğlu, Y. Developing a Resilient Healthcare Supply Chain to Prevent Disruption in the Wake of Emergency Health Crisis. Int. J. Emerg. Mark. 2022, 18, 1307–1329. [Google Scholar] [CrossRef] [Scilit]
  64. Liu, Z. Water Quality Evaluation and Guarantee Treatment of Outdoor Landscape Water. Desalin. Water Treat. 2021, 242, 195–202. [Google Scholar] [CrossRef] [Scilit]
  65. Yu, W.; Zhang, S.; Shen, H.; Yu, S.; Chen, T. Air Quality Evaluation of Bo Hai Coastal Region Based on Entropy Weight Method. J. Coast. Res. 2019, 94, 83–86. [Google Scholar] [CrossRef] [Scilit]
  66. Delgado, A.; Fernandez, A.; Chirinos, B.; Barboza, G.; Huamani Uriarte, E. Impact of the Mining Activity on the Water Quality in Peru Applying the Fuzzy Logic with the Grey Clustering Method. Int. J. Adv. Comput. Sci. Appl. 2021, 12, 348–357. [Google Scholar] [CrossRef] [Scilit]
  67. Hu, A.; Xie, N.; Zheng, M. The Journal of Grey System Air Quality Evaluation Based on Grey Clustering Method: A Case Study of 74 Cities in China. J. Grey Syst. 2019, 31, 1–27. [Google Scholar]
  68. Delgado, A.; Altaminarano, J.; Pariona, L.; Oscanoa, P.; Esquivel, S.; Mejía, W.; Carbajal, C. Grey Clustering Approach to Assess Sediment Quality in a Watershed in Peru. Int. J. Adv. Comput. Sci. Appl. 2021, 12, 229–238. [Google Scholar] [CrossRef] [Scilit]
  69. Delgado, A.; Pongo, D.; Felipa, K.; Saavedra, K.; Torres, L.; Carbajal, C. How to Analyze Air Quality During the COVID-19 Pandemic? An Answer Using Grey Systems. Int. J. Adv. Comput. Sci. Appl. 2021, 12, 408–414. [Google Scholar] [CrossRef] [Scilit]
  70. Delgado, A.; Vidal, J.; Castro, J.; Felix, J.; Saenz, J. Assessment of Surface Water Quality on the Upper Watershed of Huallaga River, in Peru, Using Grey Systems and Shannon Entropy. Int. J. Adv. Comput. Sci. Appl. 2020, 11, 437–444. [Google Scholar] [CrossRef] [Scilit]
  71. Pan, A.; Hu, L.; Li, T.; Li, C. Assessing the Eutrophication of Shengzhong Reservoir Based on Grey Clustering Method. Chin. J. Popul. Resour. Environ. 2013, 7, 83–87. [Google Scholar] [CrossRef] [Scilit]
  72. Lin, L.-W.; Chen, C.-H.; Chang, H.-C.; Chen, T.-C. Applying the Grey Assessment to the Evaluation System of Ecological Green Space on Greening Projects in Taiwan. Env. Monit. Assess. 2008, 136, 129–146. [Google Scholar] [CrossRef] [Scilit]
  73. Chen, Y.; Li, W.; Wang, X. An Investigation into the Risk Assessment of Building-Integrated Photovoltaic Residential Project Development Utilizing the DEMATEL-ANP Methodology: A Chinese Case Study. Buildings 2024, 14, 623. [Google Scholar] [CrossRef] [Scilit]
  74. Tan, Q.; Wei, T.; Peng, W.; Yu, Z.; Wu, C. Comprehensive Evaluation Model of Wind Farm Site Selection Based on Ideal Matter Element and Grey Clustering. J. Clean. Prod. 2020, 272, 122658. [Google Scholar] [CrossRef] [Scilit]
  75. Li, H.; Liu, C.; Tao, J. Gray Clustering Assessment of Environmental Cost-Benefit Study in Enterprise—A Case of Haier. J. Intell. Fuzzy Syst. 2017, 33, 2647–2656. [Google Scholar] [CrossRef] [Scilit]
  76. Huo, X.; Xue, H.; Jiao, L. Risk Management of Retrofit Project in Old Residential Areas under Green Development. Energy Build. 2023, 279, 112708. [Google Scholar] [CrossRef] [Scilit]
  77. Wang, A.; Yang, Y.; Sun, S.; Zuo, Y.; Wang, Z.; Sun, H. Developing an Evaluation Model to Measure the Intelligence Level of Smart Industrial Parks. Buildings 2022, 12, 1533. [Google Scholar] [CrossRef] [Scilit]
  78. Zhang, J.; Zhao, H.; Guo, Z. Fuzzy Gray Clustering Evaluation of Green Building Operation Effect: A Case Study of Shenzhen Bay One, China. Kybernetes 2022, 52, 5977–6000. [Google Scholar] [CrossRef] [Scilit]
  79. Wang, H.; Ying, G.; Tan, X. Study on Sustainability Evaluation and Analysis for Offshore Wind Power Projects Oriented Low-Carbon. Pol. J. Environ. Stud. 2023, 32, 853–864. [Google Scholar] [CrossRef] [Scilit]
  80. Shi, Z.; Li, Z.; Tan, X.; Hua, S. Study on Green Construction Evaluation of Highway in Seasonal Frozen Zone. J. Inf. Technol. Res. 2021, 14, 70–86. [Google Scholar] [CrossRef] [Scilit]
  81. Dong, Z.; Jiang, P.; Dai, Z.; Chi, R. What Kind of Urban Brand Ecology Attracts Talent Best? Grey Configuration Analysis of 98 Chinese Cities. Grey Syst. Theory Appl. 2024, 14, 770–788. [Google Scholar] [CrossRef] [Scilit]
  82. Tan, X.; Mao, S.; Xiao, X.; Yang, Y. Explainable Rumor Detection Based on Grey Clustering: Fusion of Manual Features and Deep Learning Features. Inf. Sci. 2024, 679, 121055. [Google Scholar] [CrossRef] [Scilit]
  83. Yu, N. The Risk Evaluation Research of Computer Network Security Based on Grey Clustering. Int. J. Secur. Its Appl. 2016, 10, 191–200. [Google Scholar] [CrossRef] [Scilit]
  84. Guo, Z.; Lu, Y.; Tian, H.; Zuo, J.; Lu, H. A Security Evaluation Model for Multi-Source Heterogeneous Systems Based on IOT and Edge Computing. Clust. Comput. 2021, 26, 303–317. [Google Scholar] [CrossRef] [Scilit]
  85. Li, L.; Zhang, K.; Li, T. A Performance Analysis Model for the Training and Education of Information Security Talents. Int. J. Emerg. Technol. Learn. 2020, 15, 140. [Google Scholar] [CrossRef] [Scilit]
  86. Duan, G.; Duan, L.; Zhou, W. Security Risk Assessment for Trusted Chain Optimizing Based on Grey Fixed Weight Clustering. J. Grey Syst. 2022, 34, 147. [Google Scholar]
  87. Tian, Q. Network Information Security Research Based on the Grey Matter Element Analysis Method. Int. J. Secur. Its Appl. 2016, 10, 107–118. [Google Scholar] [CrossRef] [Scilit]
  88. Shi, H.; Deng, Y. A Grey Model for Evaluation of Information Systems Security. JCP 2012, 7, 284–291. [Google Scholar] [CrossRef] [Scilit]
  89. Dai, Z.; Guo, X. Investigation of E-Commerce Security and Data Platform Based on the Era of Big Data of the Internet of Things. Mob. Inf. Syst. 2022, 2022, 3023298. [Google Scholar] [CrossRef] [Scilit]
  90. Yue, C.; Lu, T.; Cai, M.; Li, J. Evaluation of the Attack Effect Based on Improved Grey Clustering Model. Int. J. Digit. Crime For. 2018, 10, 92–100. [Google Scholar] [CrossRef] [Scilit]
  91. Zhao, G.; Chen, R.; Wang, J. A Cooperative Detection Scheme for Malicious Nodes Based on D-S Trust Evidence Reasoning in Mobile Crowdsensing Networks. Comput. Electr. Eng. 2024, 118, 109456. [Google Scholar] [CrossRef] [Scilit]
  92. Shao, S.; Wang, R.; Gong, A.; Li, R.; Xu, J.; Wang, F.; Liu, F. Study and Neural Network Analysis on Durability of Basalt Fibre Concrete. Water 2023, 15, 1016. [Google Scholar] [CrossRef] [Scilit]
  93. Blas García, J.; Marrufo Saldaña, L.; Barra Hinojosa, J. Evaluation of Environmental Performance of Chrome-Free Tanning Techniques of Paiche Skins (Arapaima Gigas). J. Ecol. Eng. 2022, 23, 11–24. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  94. Sandesh, S.; Vyas, A.K. A Novel Approach to High-Volume Replacement of River Sand by Waste Pond Ash in Cement Mortar Using Multicriteria Models: Engineering Properties, Sustainability Aspects, and Cost. Pract. Period. Struct. Des. Constr. 2024, 29, 04024045. [Google Scholar] [CrossRef] [Scilit]
  95. Wang, K.; Ding, W.; Luo, Q.; Ji, D.; Wang, L.; Wang, R.; Qin, X. Cleaner Dyeing Technology for Denim Fabrics with Excellent Utilization of Indigo Based on Inert Gas Protection. ACS Sustain. Chem. Eng. 2022, 10, 16009–16018. [Google Scholar] [CrossRef] [Scilit]
  96. Zhang, C.; Zhang, H.; Li, X.; Zhao, L.; Guo, L.; Qin, X. Comprehensive Wear-Ability Evaluation of Hollow Coffee Carbon Polyester/Cotton Blended Knitted Fabrics. Text. Res. J. 2022, 93, 255–265. [Google Scholar] [CrossRef] [Scilit]
  97. Song, X.; Wei, L.; Ge, M. Electromagnetic Shielding Effectiveness and Wearing Comfort of Radiation Protection Fabrics Based on Gray Clustering Analysis. J. Text. Inst. 2014, 106, 1–6. [Google Scholar] [CrossRef] [Scilit]
  98. Zhang, T.; Lan, C.; Guo, M.; Xue, W. Evaluation of Electromagnetic Shielding and Wearability of Metal Wire Composite Fabric Based on Grey Clustering Analysis. J. Text. Inst. 2015, 107, 1–8. [Google Scholar] [CrossRef] [Scilit]
  99. Wang, X.; Lin, Q.; Li, J. Energy Saving Technology of Wall Insulation of Harbor Building Based on Energy Cost Analysis. Therm. Sci. 2021, 25, 4003–4010. [Google Scholar] [CrossRef] [Scilit]
  100. Li, Y.; Shi, X.; Feng, Y.; Su, Y.; Zhang, Y.; Pu, Y.; Wang, Q. A Novel Multi-Criteria Comprehensive Evaluation Model of Fly Ash-Based Geopolymer Concrete. Constr. Build. Mater. 2023, 396, 132253. [Google Scholar] [CrossRef] [Scilit]
  101. Zhou, L.; Jiang, C.; Lin, Q. Entropy Analysis and Grey Cluster Analysis of Multiple Indexes of 5 Kinds of Genuine Medicinal Materials. Sci. Rep. 2022, 12, 6618. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  102. Llinás, H.; Gutiérrez, I.; Torresblanca, A.; De La Hoz, J.; Llinás, B. A Bibliometric and Topic Modeling Analysis of the P-Adic Theory Literature Using Latent Dirichlet Allocation. Mathematics 2025, 13, 2932. [Google Scholar] [CrossRef] [Scilit]
  103. Leon, F.; Rojas, L.; Peña, A.; Moraga, P.; Robles, P.; Gana, B.; García, J. Mathematical Modelling and Optimization Methods in Geomechanically Informed Blast Design: A Systematic Literature Review. Mathematics 2025, 13, 2456. [Google Scholar] [CrossRef] [Scilit]
  104. Domenteanu, A.; Crișan, G.-A.; Frăsineanu, C.; Delcea, C. Exploring Grey Systems in Uncertain Environments: A Bibliometric Analysis of Global Contributions and Research Themes. Sustainability 2025, 17, 2764. [Google Scholar] [CrossRef] [Scilit]
  105. Gorski, A.-T.; Ranf, E.-D.; Badea, D.; Halmaghi, E.-E.; Gorski, H. Education for Sustainability—Some Bibliometric Insights. Sustainability 2023, 15, 14916. [Google Scholar] [CrossRef] [Scilit]
  106. Stefanis, C.; Giorgi, E.; Tselemponis, G.; Voidarou, C. Terroir in View of Bibliometric. Stats 2023, 6, 956–979. [Google Scholar] [CrossRef] [Scilit]
  107. Fatma, N.; Haleem, A. Exploring the Nexus of Eco-Innovation and Sustainable Development: A Bibliometric Review and Analysis. Sustainability 2023, 15, 12281. [Google Scholar] [CrossRef] [Scilit]
  108. Delcea, C.; Domenteanu, A.; Ioanăș, C.; Vargas, V.M.; Ciucu-Durnoi, A.N. Quantifying Neutrosophic Research: A Bibliometric Study. Axioms 2023, 12, 1083. [Google Scholar] [CrossRef] [Scilit]
  109. WoS Document Types. Available online: https://webofscience.help.clarivate.com/en-us/Content/document-types.html (accessed on 13 July 2025).
  110. Donner, P. Document Type Assignment Accuracy in the Journal Citation Index Data of Web of Science. Scientometrics 2017, 113, 219–236. [Google Scholar] [CrossRef] [Scilit]
Figure 1. PRISMA flowchart.
Mathematics 13 04040 g001
Figure 2. Steps in systematic review.
Mathematics 13 04040 g002
Figure 3. Yearly scientific production.
Mathematics 13 04040 g003
Figure 4. Yearly mean citations.
Mathematics 13 04040 g004
Figure 5. Trend topics based on bigrams in titles.
Mathematics 13 04040 g005
Figure 6. Co-occurrence network for bigrams in titles.
Mathematics 13 04040 g006
Figure 7. Co-occurrence network for Keywords Plus—Biblioshiny.
Mathematics 13 04040 g007
Figure 8. Co-occurrence network for Keywords Plus—VOSviewer.
Mathematics 13 04040 g008
Figure 9. Co-occurrence network for Keywords Plus—CiteSpace.
Mathematics 13 04040 g009
Figure 10. Thematic map based on authors’ keywords, with A, B, C and D areas further depicted in Figure 11 to ensure better visibility of the extracted keywords.
Mathematics 13 04040 g010
Figure 11. Expansion upon overlapping zones (A–D) in previous figure.
Mathematics 13 04040 g011
Figure 12. Thematic map evolution on bigrams in titles.
Mathematics 13 04040 g012
Figure 13. Thematic map evolution on bigrams in titles—time slice 1989–2019.
Mathematics 13 04040 g013
Figure 14. Thematic map evolution on bigrams in titles—time slice 2020–2024.
Mathematics 13 04040 g014
Figure 15. LDA model selection—coherence score by number of topics.
Mathematics 13 04040 g015
Figure 16. LDA results [52,53].
Mathematics 13 04040 g016
Figure 17. LDA—Topic 1 [52,53].
Mathematics 13 04040 g017
Figure 18. LDA—Topic 2 [52,53].
Mathematics 13 04040 g018
Figure 19. LDA—Topic 3 [52,53].
Mathematics 13 04040 g019
Figure 20. LDA—Topic 4 [52,53].
Mathematics 13 04040 g020
Figure 21. LDA—Topic 5 [52,53].
Mathematics 13 04040 g021
Figure 22. LDA—Topic 6 [52,53].
Mathematics 13 04040 g022
Figure 23. BERTopic analysis results.
Mathematics 13 04040 g023
Figure 24. BERTopic composition.
Mathematics 13 04040 g024
Table 1. Types of grey clustering.
Type of Grey ClusteringInputsApproach to UncertaintyMain StrengthsCommon Limitations
Classical Grey Clustering (GCA)Grey numbers or interval data; evaluation indicesUses whitening weight functions to convert incomplete data into comparable grey gradesSimple, low-data requirement, interpretable resultsSensitivity to membership thresholds; limited for multidimensional problems
Weighted Grey Clustering (WGC)Same as GCA plus objective/subjective weightsWeights emphasize relative importance of criteriaBalances multi-criteria impact; widely used in evaluation systemsWeighting choice may introduce bias; computationally heavier than GCA
Grey Entropy Clustering (GEC)Raw quantitative indicators; entropy-derived weightsEntropy quantifies information uncertainty within indicatorsHandles data dispersion effectively; useful in environmental and performance evaluationEntropy assumes independence among criteria; less intuitive for non-experts
Fuzzy–Grey Clustering (FGC)Fuzzy membership values and grey relational gradesCombines fuzziness (vagueness) and greyness (incompleteness)Models linguistic uncertainty; better for qualitative assessmentsRequires parameter calibration; higher computational cost
Table 2. Main information of dataset.
IndicatorValue
Time span1989–2024
Sources159
Documents318
Annual growth rate%10.78
Average years from publication6.8
Average citations per document12.29
Co-authors per document3.65
References9292
Table 3. Document contents.
KeywordsFrequency
Keywords Plus (ID)450
Author’s Keywords (DE)1059
Table 4. Top-10 most-cited articles.
No.Paper (First Author, Journal, Reference)YearNumber of AuthorsTotal
Citations (TCs)
TC per Year (TCY)Normalised TC (NTC)
1Delgado A., Environmental Modelling & Software, [39]2016233933.9010.23
2Jiskani I.M., Resources Policy, [40]2021411022.009.59
3Sahoo S., Environmental Assessment Impact Review, [41]2016310710.703.23
4Lu Y.L., Applied Soft Computing, [42]2022510025.0010.66
5Lin C.H., Expert Systems with Applications, [43]20093744.354.21
6Ke X.L., Journal of Cleaner Production, [44]202167214.406.28
7Tsai H.C., Computer-Aided Design, [45]20063723.601.00
8Tajesh R., Measurement, [46]20181688.505.67
9Li Z.T., Ecological Indicators, [47]20195679.574.35
10Zhu J., Group Decision and Negotiation, [48]20164666.601.99
Table 5. Brief description of the content of top-10 most-cited articles.
No.Paper (First Author, Journal, Reference)YearTitleDataPurposeMethodological Category
1Delgado A., Environmental Modelling & Software, [39]2016Environmental conflict analysis using an integrated grey clustering and entropy-weight method: A case study of a mining project in PeruData was gathered from field interviews, in which some social criteria were considered.
115 individuals from urban environment
105 individuals from rural environment
35 specialists.
Analysing the environmental conflicts by using grey clustering and entropy-weight method (IGCEW), together with evaluating and comparing the mining project’s social impact, considering various perspectives from stakeholders.Empirical validation
2Jiskani I.M., Resources Policy, [40]2021Green and climate-smart mining: A framework to analyze open-pit mines for cleaner mineral productionQuantitative data from Chinese open-pit mining industry.
Technical experts’ evaluation.
Structured framework data.
Proposing a framework for assessing green and climate-smart mining (GCSM) using a case study from China.Empirical validation
3Sahoo S., Environmental Assessment Impact Review, [41]2016Environmental vulnerability assessment using grey analytic hierarchy Process-based modelThirteen factors (grouped in three main categories: natural, environmental, and human) from satellite, geographic information system, climatological, and conventional/field data.Developing and evaluating a model based on grey analytic hierarchy process for identifying zones with environmental vulnerability in a region in India.Empirical validation
4Lu Y.L., Applied Soft Computing, [42]2022Social network clustering and consensus-based distrust behaviors management for large-scale group decision-making with incomplete hesitant fuzzy preference relationsAnalytical data.
Data from a case study.
Developing and testing a framework for large-scale group decision-making in social networks (LSGDM-SN).Simulation-based
5Lin C.H., Expert Systems with Applications, [43]2009Grey clustering analysis for incipient fault diagnosis in oil-immersed transformersDissolved gas analysis (DGA) data from oil-immersed transformers.Developing and testing a method that involves grey clustering analysis (GCA) for detecting incipient faults in transformers.Empirical validation
6Ke X.L., Journal of Cleaner Production, [44]2021Urban ecological security evaluation and spatial correlation research based on data analysis of 16 cities in Hubei Province, ChinaData from 2007 to 2016, about 16 cities in China (Hubei Province), including various datasetsDeveloping and testing an urban ecological security system, with focus on 16 cities in China.Empirical validation
7Tsai H.C., Computer-Aided Design, [45]2006An image evaluation approach for parameter-based product form and color designData related to electronic door locks (330 form samples, 125 colour samples, 225 form–colour combinations, and 40 participants who rated the samples)Developing a CAD (computer-aided design) system whose main purpose is to assist designers in forecasting consumers’ perception related to products’ image, focusing on factors such as shape and colour.Empirical validation
8Tajesh R., Measurement, [46]2018Measuring the barriers to resilience in manufacturing supply chains using
grey clustering and VIKOR approaches
A case study related to an Indian electronics manufacturing firm.Identifying and ranking the key barriers in supply chain resilience.Empirical validation
9Li Z.T., Ecological Indicators, [47]2019Evaluation of ecological security and influencing factors analysis based on robustness analysis and the BP-DEMALTE model: A case study of the Pearl
River Delta urban agglomeration
Data collected from multiple sources related to 35 districts and counties from the Pearl River Delta (China).Discussing and assessing the ecological security (ES) aspects in the Pearl River Delta (China) and identifying the factors that have the greatest influence on urban ES.Empirical validation
10Zhu J., Group Decision and Negotiation, [48]2016A hierarchical clustering approach based on three-dimensional gray relational analysis for clustering a large group of decision makers with double Information15 experts who made decisions with respect to five assessment indicators. For each expert, a decision matrix and a reciprocal/complementary judgement matrix were provided.Offering a hierarchical clustering method using a 3D grey correlation degree for classifying big groups of decision makers.Theoretical contribution
Table 6. Themes with full overlap.
LDA TopicBERTopicThematic Map OverlapConsolidated Topic
LDA Topic 1: Grey Clustering for Performance Evaluation and Decision-Making FrameworksBERTopic 0: Grey Clustering for Risk and Safety Evaluation FrameworksBasic Themes: evaluation index systems, grey clustering evaluation, risk assessmentMethodological Foundations and Frameworks for Risk and Safety Evaluation
LDA Topic 2: Grey Clustering in Environmental and Water Quality AssessmentBERTopic 1: Environmental Monitoring: Water and Air Quality AssessmentBasic Themes: air/water quality; Motor Themes: environmental vulnerability, GISEnvironmental Monitoring and Assessment
Table 7. Themes with partial overlap.
LDA TopicBERTopicThematic Map OverlapConsolidated Topic
LDA Topic 3: Grey Clustering in Expert Systems and Project EvaluationBERTopic 2: Sustainable Development and Green Energy ProjectsMotor Themes: group decision-making, sustainabilityGrey Clustering in Project/Sustainability Evaluation
LDA Topic 4: Grey Clustering for Risk Assessment and Socio-Technical SystemsBERTopic 5: Information and Network SecurityNiche Themes: safety management, security evaluationGrey Clustering in Risk and Security Evaluation
LDA Topic 5: Grey Clustering in Healthcare, Industrial Processes, and Disaster Impact EvaluationBERTopic 4: Materials Science and Industrial ProcessesEmerging/Declining: industrial/materials (textile dyeing, concrete)Grey Clustering in Industrial and Material Applications
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.