1. Introduction
The Lindley distribution, originally introduced by Lindley [
1], has emerged as a versatile and practical model in reliability analysis, survival studies, and applied probability. Its popularity stems from its simple yet flexible one-parameter structure, which allows it to effectively model lifetime and waiting-time data exhibiting skewness and nonmonotone hazard rates. Compared to classical distributions such as the exponential or gamma, the Lindley distribution often provides a superior fit for small to moderate sample sizes, offering enhanced interpretability and computational convenience; see Qayoom et al. [
2] for additional details. Its applications span diverse fields, including engineering reliability, health sciences, actuarial studies, and queuing systems, highlighting its importance as a tool for modeling stochastic phenomena.
Despite its widespread application, the Lindley distribution is constrained by a monotonically decreasing hazard function, limiting its flexibility in capturing a range of lifetime behaviors. To address this limitation, a modern enhancement of the classical Lindley family, named the ZLindley distribution, has been introduced by Saaidia et al. [
3] as a combination of exponential and gamma components, thereby extending the adaptability of traditional models like the Lindley distribution. This development expands upon the classical Lindley model by adding an additional linear term to its density expression, which enhances flexibility in modeling lifetime data characterized by varying hazard rate behaviors. Unlike the classical Lindley and other simple lifetime distributions, the ZLindley (ZL(
)) distribution exhibits improved adaptability in capturing a broad spectrum of hazard rate behaviors, including increasing and near-constant shapes, making it well-suited for heterogeneous reliability and survival data. Its statistical properties, such as closed-form expressions for the probability density and distribution functions, central tendency measures, and reliability characteristics, have been rigorously derived, facilitating both theoretical analysis and practical implementation. Empirical studies demonstrate that the ZL(
) model often outperforms several classical competitors (e.g., Lindley, Weibull, Gamma) in goodness-of-fit for real datasets, underscoring its advantage in modeling over-dispersion and complex lifetime dynamics; see Alotaibi and Elshahhat [
4].
A random variable
X is said to follow the one-parameter ZL distribution (with
is a scale) if its probability density function (PDF), denoted by
, and corresponding cumulative distribution function (CDF), denoted by
, are given respectively by
and
see, for more details, Mahnashi and Zaagan [
5]. The inversion technique is a powerful approach in statistical modeling, developed by applying a reciprocal transformation to a positive random variable. This method produces inverted distributions with enhanced flexibility, allowing the generation of diverse hazard rate behaviors, including upside-down bathtub (inverted-bathtub) shapes, which is particularly valuable for systems exhibiting high early risk followed by stabilization. Inverted distributions often provide superior fits for real-world data compared to classical lifetime models, especially in contexts where large survival times, low failure rates, or extreme events are prevalent; see Sharma et al. [
6], Nguyen et al. [
7], Tomer and Panwar [
8], Choudhary et al. [
9], Alqasem et al. [
10], and Singh et al. [
11], among others.
Classical one-parameter lifetime models are attractive because of their simplicity and easy interpretation. However, they often become inadequate when observed hazard rates are non-monotone. Many practical systems exhibit an upside-down bathtub (UBT) hazard shape, where failure risk first increases and then decreases. Such behavior cannot be captured well by exponential, Lindley, or other monotone one-parameter models. One important example arises in communication engineering systems such as sensors, wireless nodes, and transceivers. These devices may suffer early failures due to calibration errors, manufacturing defects, or installation stress before becoming stable later. Another example occurs in environmental health after exposure to pollutants, radiation, or toxic chemicals. In such cases, health risk may initially rise and then decline because of adaptation, treatment, or removal of highly susceptible individuals. Similar patterns also appear in industrial units exposed to transient overload or frictional adjustment during early operation. These practical limitations motivate the proposed inverted ZLindley (IZL) model as a parsimonious one-parameter model with UBT hazard flexibility.
In the next section, we introduce the IZL model that preserves analytical simplicity while substantially enriching hazard-rate behavior. The main objectives of the current study can be summarized fourfold as follows:
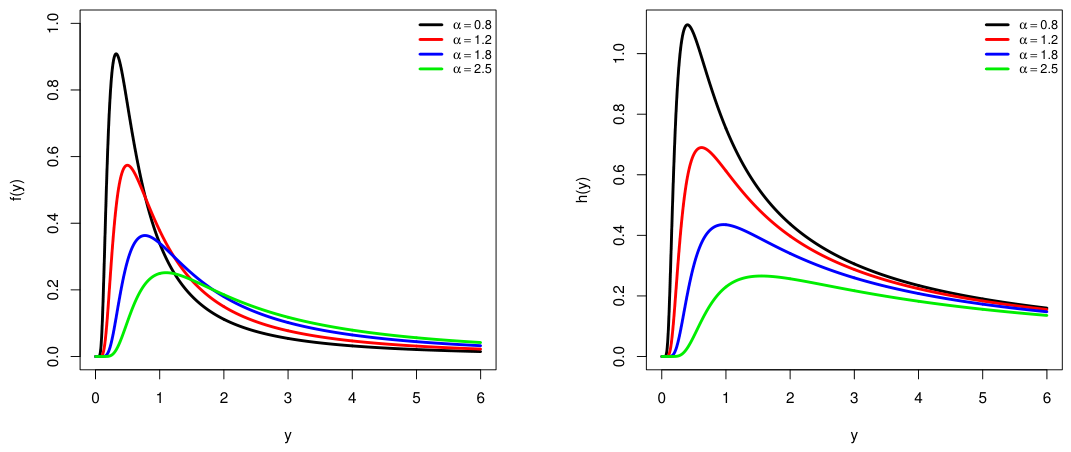
A new IZL model is proposed, providing a flexible distributional form capable of capturing UBT failure rate behavior while retaining the simplicity of a single-parameter structure. The probability density and hazard rate functions are analytically shown to be strictly positive, unimodal, and heavy-tailed, with the hazard rate exhibiting a UBT shape—an essential feature for modeling early-risk-dominated systems.
Parameter estimation is developed under Type-II censored samples (T2CSs), including existence and uniqueness of the maximum likelihood, Bayesian estimation with informative gamma prior, and implementation via MCMC methods. Six interval estimation approaches are proposed and compared, including asymptotic, bootstrap, Bayesian credible, and HPD intervals, providing a comprehensive inferential toolkit.
Comprehensive simulations assess estimator accuracy, bias, interval length, and coverage probability, demonstrating the superior finite-sample performance of Bayesian and HPD-based procedures, particularly under censoring.
The adaptability of the proposed IZL distribution is demonstrated through two real datasets drawn from environmental health and communication engineering, both of which naturally exhibit heavy-tailed behavior, positive skewness, and non-monotone failure dynamics. These features are difficult to capture simultaneously using existing inverted lifetime models. To rigorously assess adequacy, the IZL model is benchmarked against 15 well-established inverted distributions using likelihood-based, information-theoretic, and goodness-of-fit criteria. Across both applications, the IZL model consistently emerges as the most competitive compared to inverted Lindley, inverted X-Lindley, inverted gamma, inverted Weibull, inverted Chen, and inverted Nadarajah–Haghighi, among others.
The rest of this work is classified as follows:
Section 2 introduces the proposed IZL model and presents its fundamental definitions.
Section 3 derives key statistical and reliability properties. In
Section 4 and
Section 5, several point and interval parameter estimation procedures are investigated, respectively. The simulation design of the estimators is done in
Section 6. Two real data applications from communication engineering and environmental health are analyzed in
Section 7. Finally,
Section 8 provides the concluding remarks and future research directions.
6. Monte Carlo Comparisons
To investigate the finite-sample performance of the proposed estimators for the IZL parameter introduced in the preceding sections, comprehensive Monte Carlo comparisons are conducted. In particular, T2CSs are generated under various experimental settings to evaluate both point and interval estimation procedures. The simulation design is summarized in Algorithm 3. In this algorithm, we examine three levels of failure percentage (FP), namely 50%, 80%, and 100%. When the FP reaches 100%, the T2CS sample is effectively updated into a complete sample.
| Algorithm 3 Simulation Designs for the IZL Model Under T2CS |
| 1: Set Pop-1: IZL and Pop-2: IZL. |
| 2: Set . |
| 3: For , generate independently. |
| 4: Compute , where denotes the IZL quantile function. |
| 5: Fix failure percentages , where . |
| 6: Compute MLEs, ACIs, bootstrap CIs, and MCMC with BCI/HPD intervals. |
| 7: Repeat Steps 3–6 independently for Monte Carlo replications. |
| 8: Evaluate estimators using MSE, MAB, AIL, and CP measures as |
|
| where denotes the indicator function. |
To complete the Bayesian analysis (including MCMC and BCIHPD estimates) of , by taking and , two informative gamma prior settings are considered as follows:
For Pop-1: Prior-1 and Prior-2 .
For Pop-2: Prior-1 and Prior-2 .
By employing two recommended
packages, namely
maxLik for likelihood-based optimization and coda for Bayesian posterior analysis and MCMC diagnostics, as recommended by Henningsen and Toomet [
14] and Plummer et al. [
17], respectively, all classical and Bayesian estimates along with their corresponding interval estimates are obtained. The complete set of computational scripts used in this study is available from the authors upon reasonable request.
Table 1 and
Table 2 summarize the Monte Carlo results in terms of MSE, MAB, AIL, and CP for the IZL parameter
. The main findings can be summarized as follows:
Increasing the sample size n leads to substantial improvements in estimation accuracy for all considered estimators, while similar gains are observed as the failure percentage (FP%) increases.
As FP% approaches (complete case), both point and interval estimators exhibit increasingly satisfactory performance, in agreement with the expected asymptotic behavior of the estimators.
Bayesian estimators constructed under informative priors consistently outperform likelihood-based estimators in terms of MSE and MAB, reflecting the benefit of incorporating prior information.
Comparing the asymptotic methods, the ACI-NA approach generally performs better than the ACI-NL method, achieving more accurate CPs in addition to smaller AILs.
Comparing the bootstrap methods, the Boot-t approach outperforms the Boot-p method, in terms of smallest AILs and largest CPs.
Comparing the credible methods, the HPD intervals dominate percentile-based BCIs, as they provide narrower intervals with improved coverage accuracy.
Both 95% BCI and HPD intervals demonstrate superior performance compared to asymptotic (ACI-NA and ACI-NL) and bootstrap (Boot-p and Boot-t) methods, yielding shorter AILs and higher CPs.
For Bayesian estimation, Prior-2 consistently outperforms Prior-1, which can be attributed to its smaller prior variance and stronger informativeness.
Although both prior specifications yield comparable point estimates, the more informative Prior-2 results in enhanced precision, reflected by reduced MSEs and shorter interval lengths; nevertheless, the overall sensitivity to prior choice remains moderate, confirming the robustness of the Bayesian procedure.
As the true value of increases, the associated MSE, MAB, and AIL values tend to increase, while the corresponding coverage probabilities decrease.
Overall, Bayesian estimation implemented via a Markov iterative algorithm with a normal proposal distribution is recommended for reliable and efficient estimation of the IZL model parameter.
Table 1.
The MSEs (1st Col.) and MABs (2nd Col.) of .
Table 1.
The MSEs (1st Col.) and MABs (2nd Col.) of .
| FP% | n | Pop-1 | Pop-2 |
|---|
| MSE | MAB | MSE | MAB |
|---|
| MLE | Bayes-P1 | Bayes-P2 | MLE | Bayes-P1 | Bayes-P2 | MLE | Bayes-P1 | Bayes-P2 | MLE | Bayes-P1 | Bayes-P2 |
|---|
| 50% | 20 | 0.0901 | 0.0766 | 0.0747 | 0.0138 | 0.0103 | 0.0094 | 0.2784 | 0.1883 | 0.1732 | 0.1336 | 0.0619 | 0.0459 |
| | 50 | 0.0495 | 0.0482 | 0.0448 | 0.0038 | 0.0037 | 0.0032 | 0.1484 | 0.1318 | 0.1313 | 0.0351 | 0.0270 | 0.0266 |
| | 100 | 0.0379 | 0.0339 | 0.0337 | 0.0022 | 0.0019 | 0.0018 | 0.1167 | 0.0998 | 0.0951 | 0.0206 | 0.0163 | 0.0149 |
| | 150 | 0.0312 | 0.0303 | 0.0287 | 0.0016 | 0.0013 | 0.0012 | 0.0958 | 0.0888 | 0.0858 | 0.0149 | 0.0116 | 0.0110 |
| | 200 | 0.0257 | 0.0243 | 0.0240 | 0.0010 | 0.0009 | 0.0009 | 0.0790 | 0.0733 | 0.0712 | 0.0097 | 0.0082 | 0.0078 |
| 80% | 20 | 0.0899 | 0.0744 | 0.0737 | 0.0138 | 0.0099 | 0.0087 | 0.2776 | 0.1869 | 0.1687 | 0.1331 | 0.0607 | 0.0434 |
| | 50 | 0.0481 | 0.0481 | 0.0446 | 0.0037 | 0.0036 | 0.0031 | 0.1480 | 0.1313 | 0.1278 | 0.0351 | 0.0268 | 0.0252 |
| | 100 | 0.0379 | 0.0338 | 0.0337 | 0.0022 | 0.0018 | 0.0018 | 0.1167 | 0.0997 | 0.0950 | 0.0206 | 0.0162 | 0.0148 |
| | 150 | 0.0311 | 0.0302 | 0.0286 | 0.0016 | 0.0013 | 0.0012 | 0.0956 | 0.0885 | 0.0853 | 0.0148 | 0.0115 | 0.0108 |
| | 200 | 0.0257 | 0.0235 | 0.0235 | 0.0010 | 0.0008 | 0.0008 | 0.0789 | 0.0713 | 0.0696 | 0.0097 | 0.0077 | 0.0075 |
| 100% | 20 | 0.0895 | 0.0740 | 0.0736 | 0.0137 | 0.0098 | 0.0087 | 0.2763 | 0.1862 | 0.1684 | 0.1324 | 0.0599 | 0.0431 |
| | 50 | 0.0480 | 0.0480 | 0.0444 | 0.0037 | 0.0036 | 0.0031 | 0.1477 | 0.1313 | 0.1278 | 0.0349 | 0.0266 | 0.0251 |
| | 100 | 0.0371 | 0.0338 | 0.0335 | 0.0021 | 0.0018 | 0.0018 | 0.1143 | 0.0994 | 0.0948 | 0.0197 | 0.0161 | 0.0147 |
| | 150 | 0.0310 | 0.0296 | 0.0285 | 0.0016 | 0.0013 | 0.0012 | 0.0952 | 0.0868 | 0.0852 | 0.0148 | 0.0114 | 0.0108 |
| | 200 | 0.0255 | 0.0235 | 0.0234 | 0.0010 | 0.0008 | 0.0008 | 0.0784 | 0.0709 | 0.0696 | 0.0096 | 0.0077 | 0.0074 |
Table 2.
The AILs (1st Col.) and CPs (2nd Col.) of .
Table 2.
The AILs (1st Col.) and CPs (2nd Col.) of .
| FP% | n | ACI-NA | ACI-NL | Boot-p | Boot-t | BCI-P1 | BCI-P2 | HPD-P1 | HPD-P2 |
|---|
| | | Pop-1 |
| 50% | 20 | 0.414 | 0.937 | 0.411 | 0.938 | 0.404 | 0.939 | 0.392 | 0.941 | 0.380 | 0.943 | 0.375 | 0.944 | 0.360 | 0.946 | 0.355 | 0.947 |
| | 50 | 0.244 | 0.967 | 0.242 | 0.967 | 0.242 | 0.967 | 0.240 | 0.968 | 0.238 | 0.968 | 0.238 | 0.968 | 0.237 | 0.968 | 0.236 | 0.968 |
| | 100 | 0.173 | 0.979 | 0.172 | 0.979 | 0.170 | 0.980 | 0.170 | 0.980 | 0.170 | 0.980 | 0.169 | 0.980 | 0.169 | 0.980 | 0.168 | 0.980 |
| | 150 | 0.142 | 0.985 | 0.142 | 0.985 | 0.140 | 0.985 | 0.139 | 0.985 | 0.139 | 0.985 | 0.138 | 0.985 | 0.138 | 0.985 | 0.136 | 0.986 |
| | 200 | 0.122 | 0.988 | 0.122 | 0.988 | 0.122 | 0.988 | 0.120 | 0.989 | 0.120 | 0.989 | 0.120 | 0.989 | 0.119 | 0.989 | 0.119 | 0.989 |
| 80% | 20 | 0.410 | 0.938 | 0.403 | 0.939 | 0.401 | 0.939 | 0.389 | 0.941 | 0.375 | 0.944 | 0.371 | 0.945 | 0.357 | 0.947 | 0.352 | 0.948 |
| | 50 | 0.241 | 0.967 | 0.239 | 0.968 | 0.239 | 0.968 | 0.238 | 0.968 | 0.236 | 0.968 | 0.236 | 0.968 | 0.235 | 0.968 | 0.232 | 0.969 |
| | 100 | 0.173 | 0.979 | 0.172 | 0.979 | 0.170 | 0.980 | 0.170 | 0.980 | 0.170 | 0.980 | 0.169 | 0.980 | 0.168 | 0.980 | 0.167 | 0.980 |
| | 150 | 0.141 | 0.985 | 0.140 | 0.985 | 0.138 | 0.985 | 0.137 | 0.986 | 0.137 | 0.986 | 0.137 | 0.986 | 0.137 | 0.986 | 0.135 | 0.986 |
| | 200 | 0.121 | 0.988 | 0.120 | 0.988 | 0.120 | 0.988 | 0.119 | 0.989 | 0.119 | 0.989 | 0.119 | 0.989 | 0.118 | 0.989 | 0.118 | 0.989 |
| 100% | 20 | 0.410 | 0.938 | 0.401 | 0.939 | 0.400 | 0.939 | 0.389 | 0.941 | 0.374 | 0.944 | 0.369 | 0.945 | 0.357 | 0.947 | 0.352 | 0.948 |
| | 50 | 0.241 | 0.967 | 0.239 | 0.968 | 0.239 | 0.968 | 0.238 | 0.968 | 0.236 | 0.968 | 0.235 | 0.968 | 0.234 | 0.968 | 0.232 | 0.969 |
| | 100 | 0.171 | 0.980 | 0.170 | 0.980 | 0.168 | 0.980 | 0.168 | 0.980 | 0.167 | 0.980 | 0.167 | 0.980 | 0.167 | 0.980 | 0.166 | 0.980 |
| | 150 | 0.141 | 0.985 | 0.140 | 0.985 | 0.138 | 0.985 | 0.137 | 0.986 | 0.137 | 0.986 | 0.136 | 0.986 | 0.136 | 0.986 | 0.135 | 0.986 |
| | 200 | 0.121 | 0.988 | 0.120 | 0.988 | 0.120 | 0.988 | 0.119 | 0.989 | 0.119 | 0.989 | 0.118 | 0.989 | 0.118 | 0.989 | 0.117 | 0.989 |
| | | Pop-2 |
| 50% | 20 | 1.268 | 0.921 | 1.215 | 0.924 | 1.175 | 0.927 | 1.165 | 0.927 | 1.145 | 0.929 | 1.025 | 0.936 | 0.955 | 0.941 | 0.920 | 0.943 |
| | 50 | 0.754 | 0.953 | 0.764 | 0.953 | 0.734 | 0.954 | 0.726 | 0.955 | 0.715 | 0.956 | 0.693 | 0.957 | 0.671 | 0.958 | 0.662 | 0.959 |
| | 100 | 0.531 | 0.967 | 0.528 | 0.967 | 0.522 | 0.968 | 0.522 | 0.968 | 0.508 | 0.969 | 0.504 | 0.969 | 0.500 | 0.969 | 0.492 | 0.970 |
| | 150 | 0.433 | 0.973 | 0.431 | 0.973 | 0.421 | 0.974 | 0.421 | 0.974 | 0.421 | 0.974 | 0.417 | 0.974 | 0.407 | 0.975 | 0.404 | 0.975 |
| | 200 | 0.371 | 0.977 | 0.370 | 0.977 | 0.370 | 0.977 | 0.366 | 0.977 | 0.358 | 0.978 | 0.358 | 0.978 | 0.356 | 0.978 | 0.355 | 0.978 |
| 80% | 20 | 1.207 | 0.925 | 1.127 | 0.930 | 1.008 | 0.937 | 1.100 | 0.932 | 1.044 | 0.935 | 1.022 | 0.936 | 0.924 | 0.943 | 0.910 | 0.943 |
| | 50 | 0.741 | 0.954 | 0.735 | 0.954 | 0.713 | 0.956 | 0.703 | 0.956 | 0.690 | 0.957 | 0.691 | 0.957 | 0.671 | 0.958 | 0.662 | 0.959 |
| | 100 | 0.526 | 0.967 | 0.523 | 0.968 | 0.517 | 0.968 | 0.513 | 0.968 | 0.505 | 0.969 | 0.501 | 0.969 | 0.451 | 0.972 | 0.427 | 0.974 |
| | 150 | 0.432 | 0.973 | 0.431 | 0.973 | 0.420 | 0.974 | 0.420 | 0.974 | 0.420 | 0.974 | 0.416 | 0.974 | 0.406 | 0.975 | 0.402 | 0.975 |
| | 200 | 0.371 | 0.977 | 0.370 | 0.977 | 0.370 | 0.977 | 0.366 | 0.977 | 0.358 | 0.978 | 0.358 | 0.978 | 0.355 | 0.978 | 0.355 | 0.978 |
| 100% | 20 | 0.850 | 0.947 | 0.786 | 0.951 | 0.743 | 0.954 | 0.732 | 0.955 | 0.725 | 0.955 | 0.697 | 0.957 | 0.680 | 0.958 | 0.671 | 0.958 |
| | 50 | 0.583 | 0.964 | 0.591 | 0.963 | 0.552 | 0.966 | 0.532 | 0.967 | 0.521 | 0.968 | 0.510 | 0.968 | 0.501 | 0.969 | 0.496 | 0.969 |
| | 100 | 0.437 | 0.973 | 0.436 | 0.973 | 0.426 | 0.974 | 0.426 | 0.974 | 0.425 | 0.974 | 0.422 | 0.974 | 0.411 | 0.975 | 0.405 | 0.975 |
| | 150 | 0.375 | 0.977 | 0.374 | 0.977 | 0.374 | 0.977 | 0.369 | 0.977 | 0.363 | 0.978 | 0.361 | 0.978 | 0.360 | 0.978 | 0.358 | 0.978 |
| | 200 | 0.302 | 0.982 | 0.301 | 0.982 | 0.301 | 0.982 | 0.298 | 0.982 | 0.297 | 0.982 | 0.297 | 0.982 | 0.294 | 0.982 | 0.294 | 0.982 |
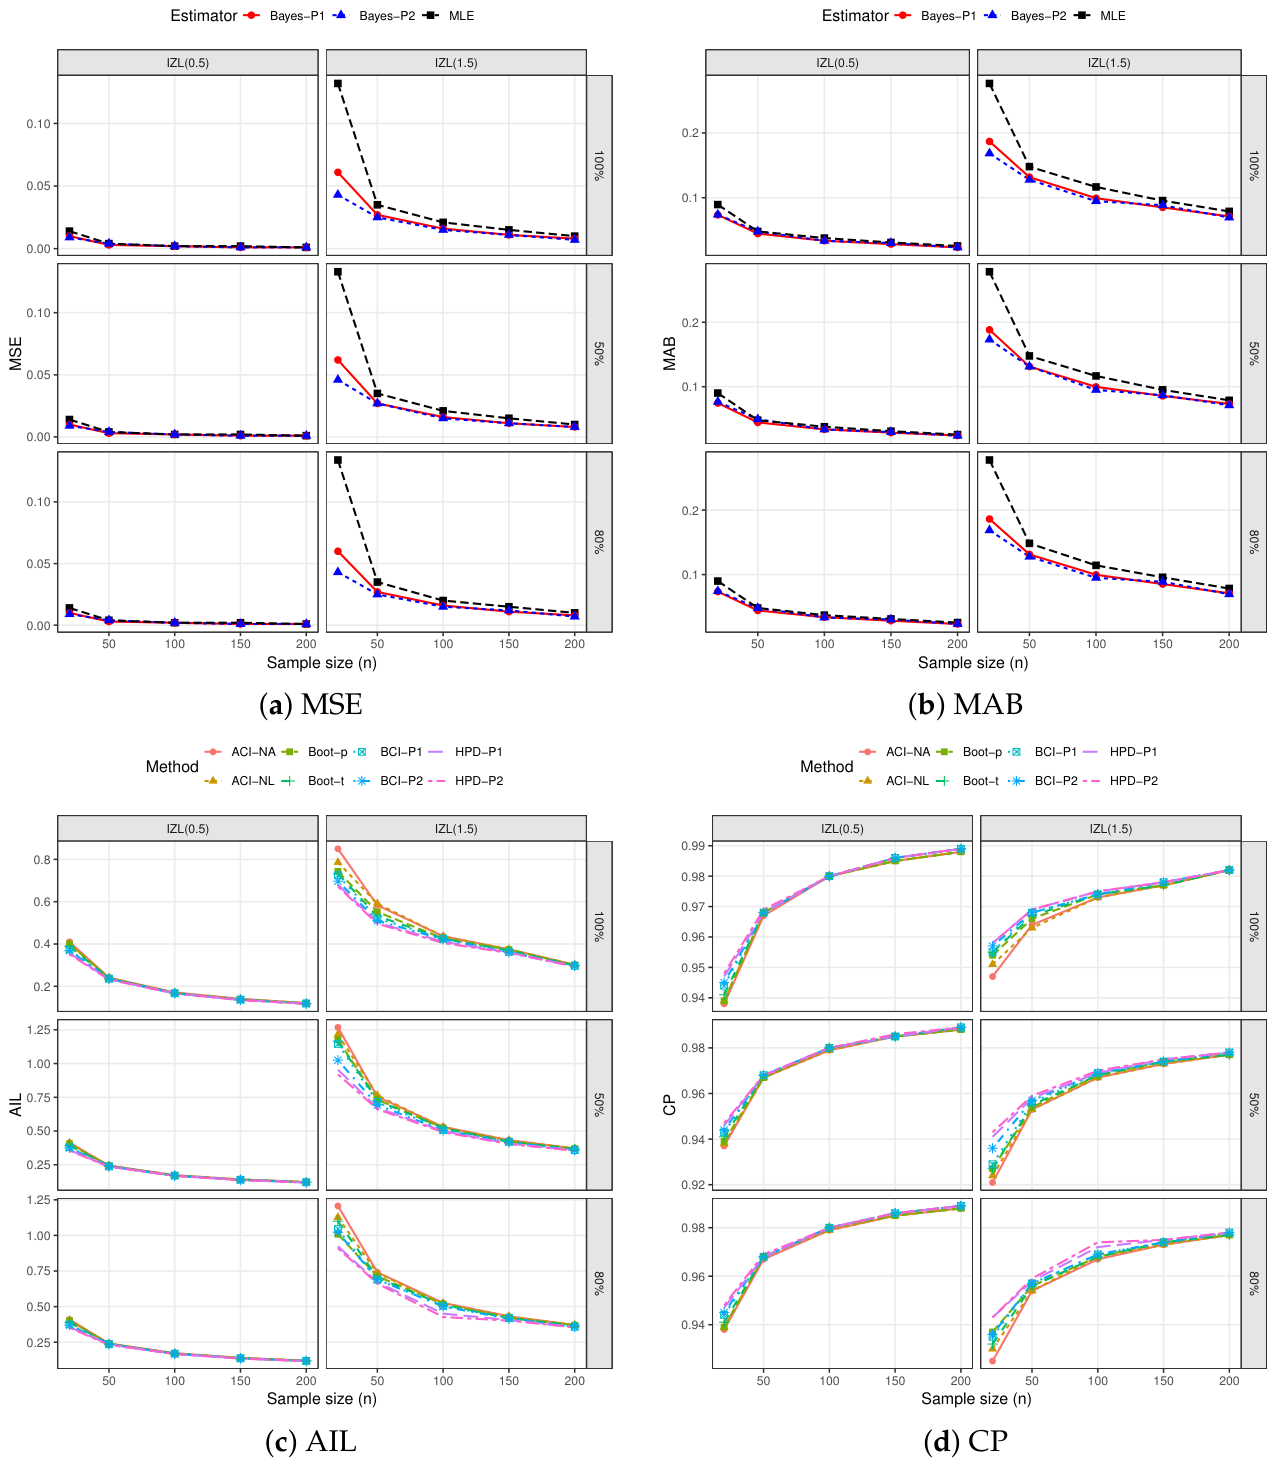
Figure 4 presents the simulation results for the IZL
model, summarizing the performance of competing estimators and interval construction methods across varying sample sizes and censoring proportions. The subplots in
Figure 4a,b show that both MSE and MAB decrease steadily as the sample size increases, confirming the consistency of all estimators, with the Bayesian procedures (especially Bayes–P2) generally outperforming the MLE in small samples. The advantage of the Bayesian estimators is most pronounced under heavier censoring and smaller
, where the MLE exhibits noticeably higher variability.
Figure 4c indicates that the AIL shrinks with increasing sample size, while BCIs, particularly HPD-based methods, tend to achieve shorter intervals compared to ACI-NA and ACI-NL methods without sacrificing stability. In
Figure 4d, the CP approaches the nominal level as
n grows, with Bayesian intervals showing slightly better adherence to the target level in small samples and under higher censoring. Overall, the results suggest that Bayesian approaches provide improved efficiency and more reliable interval estimation for the IZL
model, especially in challenging sampling scenarios. Additionally, all facts shown in
Figure 4 support the same findings reported in
Table 1 and
Table 2.
7. Data Analysis
This section considers two real datasets gathered from engineering and health sciences, demonstrating the versatility and practical value of advanced inferential methods. The first dataset addresses environmental health by modeling the relationship between airborne contaminant exposure and urinary metabolite concentrations. In contrast, the second examines engineering reliability through the analysis of active repair times for airborne communication transceivers. Below, and before presenting these datasets in the
Table 3, we offer the following brief discussion:
- Data A:
Variations in airborne exposure levels to environmental contaminants can significantly influence the concentration of corresponding urinary metabolites, serving as critical biomarkers of internal dose. Understanding these fluctuations in airborne contaminant concentrations is reflected in urinary metabolite concentrations (UMCs), highlighting the dynamic relationship between external exposure and internal biological response; see Kumagai and Matsunaga [
18]. We will reanalyze a dataset from Peter et al. [
19] that includes 31 effects of variations in airborne exposure on UMC percentages.
- Data B:
Airborne communication transceivers (ACTs) are critical components in aviation systems, and their active repair times constitute a key performance metric that directly influences operational readiness and mission continuity; see Tooley and Wyatt [
20], for more details. These repair times show how well maintenance works, how complicated the transceiver hardware is, and how easily diagnostic tools can be accessed in both normal and urgent situations. This application examines 40 observations (measured in hours) of the active repair times for ACTs; see Jorgensen [
21].
Table 3.
Datasets from engineering and health sciences.
Table 3.
Datasets from engineering and health sciences.
| Data | Items |
|---|
| UMC | 1.5 | 1.7 | 2.1 | 2.2 | 2.4 | 2.5 | 2.6 | 3.8 | 3.8 | 4.2 | 4.3 | 5.6 |
| | 6.0 | 7.0 | 7.5 | 9.3 | 9.9 | 10.2 | 10.6 | 12.3 | 12.9 | 13.7 | 14.1 | 17.8 |
| | 27.6 | 31.0 | 42.0 | 45.6 | 51.9 | 91.3 | 131.8 | | | | | |
|
ACT | 0.50 | 0.60 | 0.60 | 0.70 | 0.70 | 0.70 | 0.80 | 0.80 | 1.00 | 1.00 | 1.00 | 1.00 |
| | 1.10 | 1.30 | 1.50 | 1.50 | 1.50 | 1.50 | 2.00 | 2.00 | 2.20 | 2.50 | 2.70 | 3.00 |
| | 3.00 | 3.30 | 4.00 | 4.00 | 4.50 | 4.70 | 5.00 | 5.40 | 5.40 | 7.00 | 7.50 | 8.80 |
| | 9.00 | 10.20 | 22.00 | 24.50 | | | | | | | | |
Before proceeding further, the adequacy, flexibility, and practical effectiveness of the proposed IZL model are empirically assessed using the complete UMC and ACT datasets. Specifically, the fit performance of the IZL distribution is benchmarked against a comprehensive set of fifteen well-known inverted lifetime distributions available in the literature:
- (1)
Inverted X-Lindley (IXL(
)) by Beghriche et al. [
22];
- (2)
Inverted Lindley (IL(
)) by Sharma et al. [
6];
- (3)
Inverted exponential (IE(
)) by Keller et al. [
23];
- (4)
Inverted Weibull (IW(
)) by Ramos et al. [
24];
- (5)
Inverted gamma (IG(
)) by Glen [
25];
- (6)
Inverted Chen (IC(
)) by Srivastava and Srivastava [
26];
- (7)
Inverted Kumaraswamy (IK(
)) by Abd AL-Fattah et al. [
27];
- (8)
Inverted Pham (IP(
)) by Alqasem et al. [
10].
- (9)
Inverted exponentiated Pareto (IEP(
)) by Abouammoh and Alshingiti [
28];
- (10)
Exponentiated inverted exponential (EIE(
)) by Fatima and Ahmad [
29];
- (11)
Generalized inverted exponential (GIE(
)) by Abouammoh and Alshingiti [
28];
- (12)
Inverted Nadarajah–Haghighi (INH(
)) by Tahir et al. [
30];
- (13)
Inverted Lomax (ILo(
)) by Kleiber and Kotz [
31];
- (14)
Alpha-power inverted exponential (APIE(
)) by Ünal et al. [
32];
- (15)
Generalized inverted half-logistic (GIHL(
)) by Potdar and Shirke [
33].
The comparative adequacy of the IZL distribution relative to the competing lifetime models is examined using a collection of standard goodness-of-fit measures. Specifically, we consider (i) the negative log-likelihood (
), (ii) the Akaike information criterion (
), (iii) the consistent AIC (
), (iv) the Bayesian information criterion (
), (v) the Hannan–Quinn information criterion (
), and (vi) the Kolmogorov–Smirnov (
) statistic together with its corresponding
P-value. In
Table 4, the aforementioned goodness-of-fit measures (i)–(vi) are computed using the MLEs of
and
, along with their associated standard errors (Std.Ers). Inspection of
Table 4 indicates that the proposed IZL distribution attains the lowest values across all considered metrics, while also yielding the highest
p-value. These results collectively suggest that the IZL model provides a superior fit compared to the competing distributions, supporting its recommendation as the most appropriate model for the datasets under consideration.
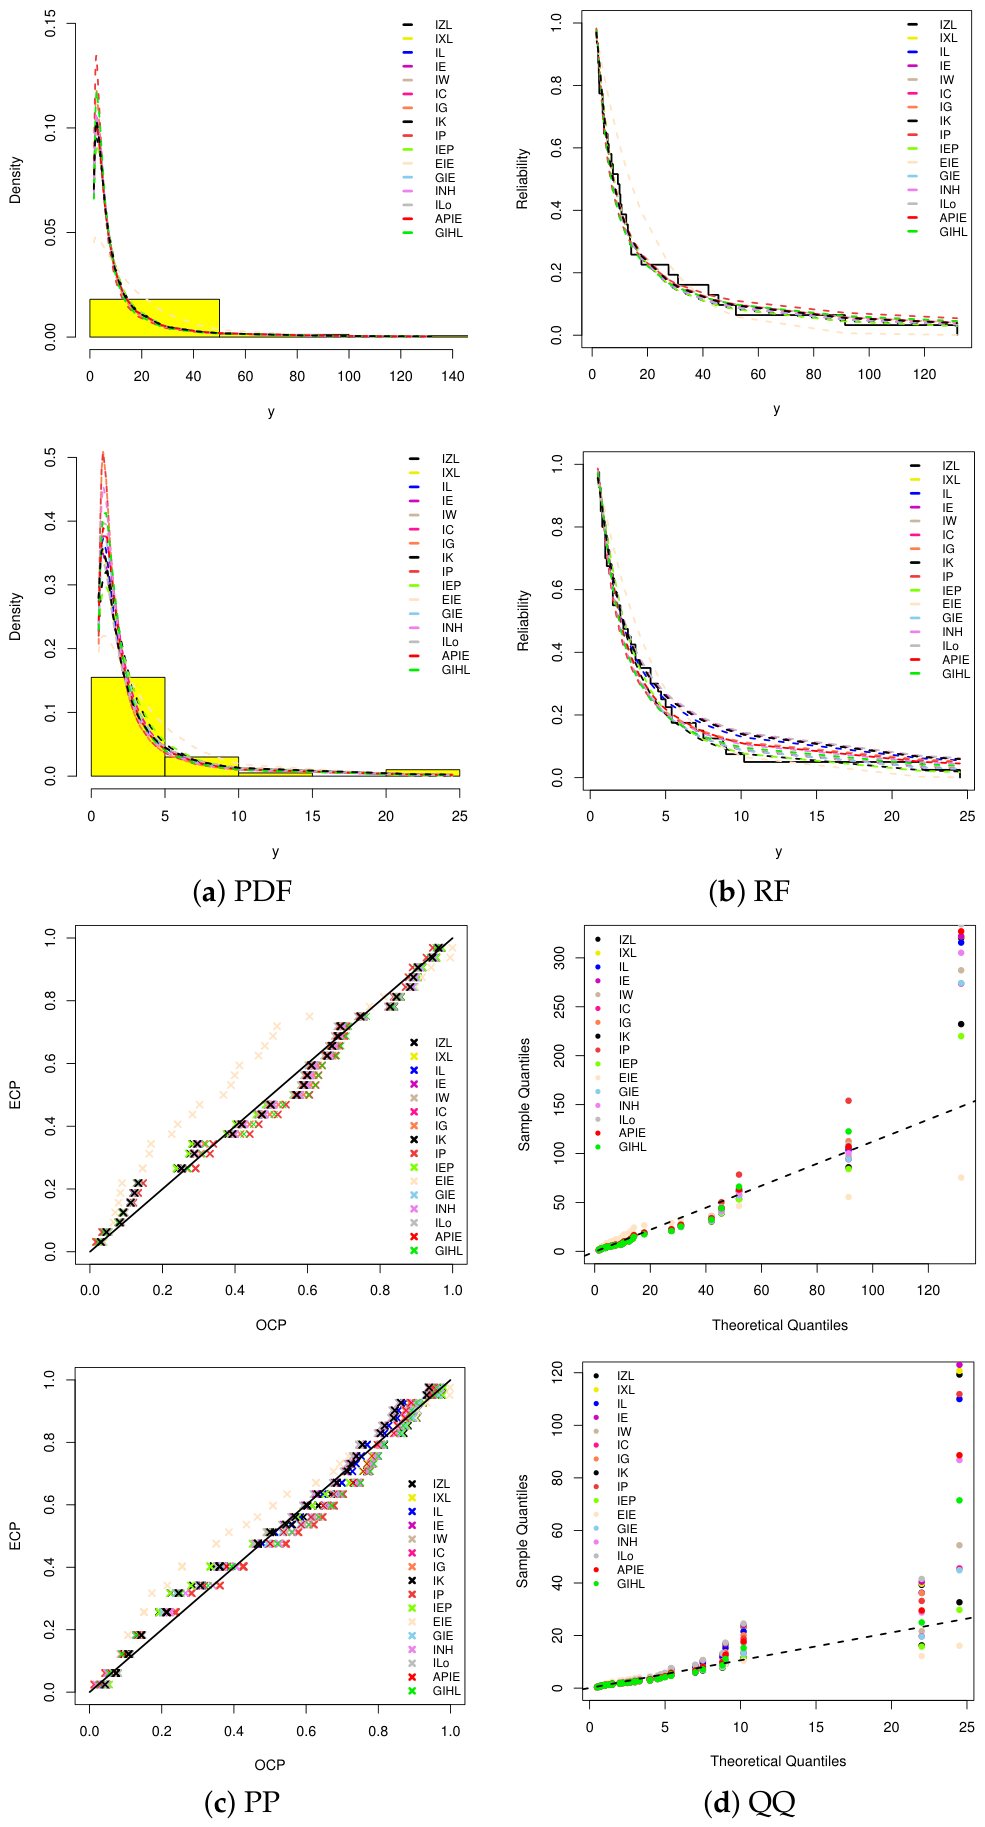
Figure 5 presents a comprehensive set of graphical goodness-of-fit diagnostics, the estimated PDF lines on UMC and ACT data histograms, and estimated/empirical lines of RF, P–P, and Q–Q functions to assess the adequacy of the proposed IZL distribution relative to several competing lifetime models. These diagnostics are applied to the UMC and ACT datasets to visually compare how well each model captures the empirical behavior of the observed data. Such graphical tools complement numerical fit criteria by revealing discrepancies in distributional shape, tail behavior, and overall agreement with empirical probabilities. Across both datasets, as shown in
Figure 5, the IZL model exhibits closer alignment with the empirical distributions, as evidenced by tighter PDF overlays and P–P/Q–Q points lying nearer to the theoretical lines. This visual consistency supports the claim that the IZL distribution provides a superior or at least competitive fit, particularly in modeling skewness and tail characteristics of lifetime data.
Additionally,
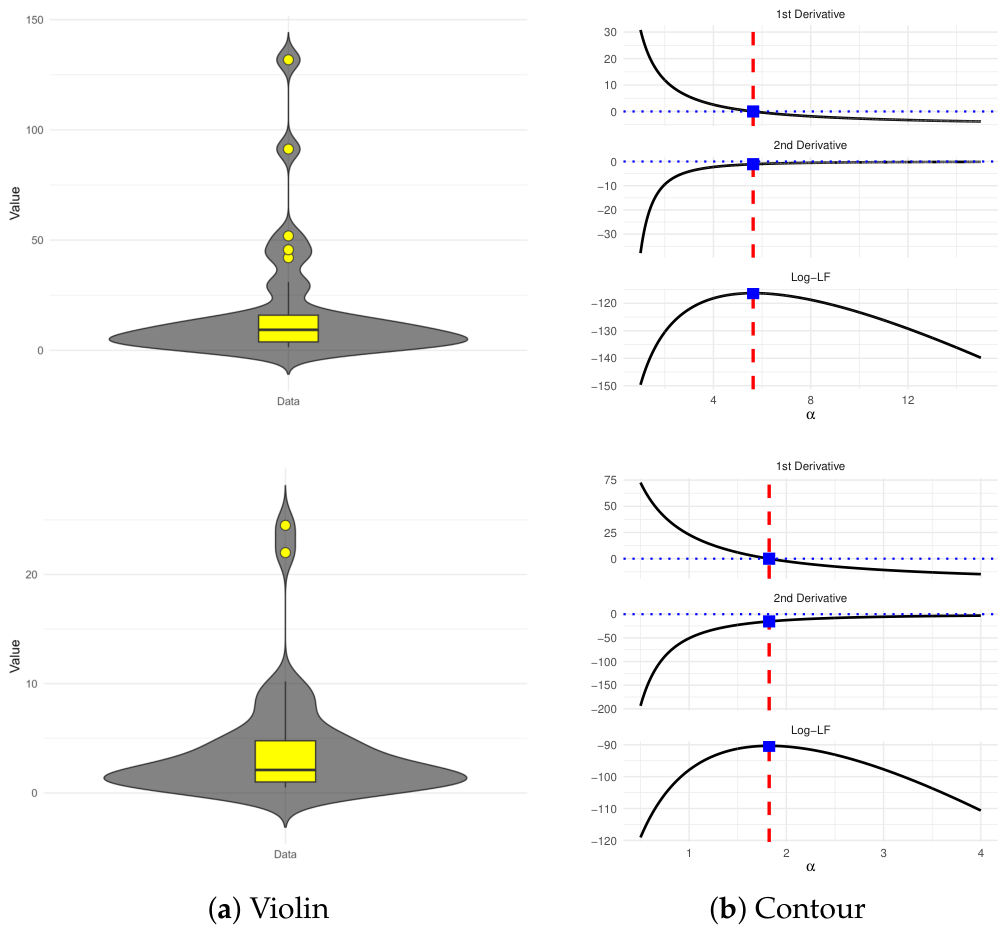
Figure 6a,b illustrate complementary graphical tools for understanding the data structure and the behavior of the likelihood function in parameter estimation. The violin plots summarize the empirical distributions, highlighting skewness, dispersion, and the presence of extreme observations in each dataset.
It is worth noticing here that the proposed IZL distribution combines the ability to model a UBT hazard rate, positive skewness, and heavy-tailed behavior within a one-parameter framework. Hence, flexibility is reflected not only through numerical differences in the statistics fitted in
Table 4 but also through the capacity to represent important lifetime mechanisms using a simple and interpretable model. It is also worth emphasizing that, in both the ACT and UMC datasets taken from communication engineering and environmental health, respectively, the IZL model attained the most competitive overall fit according to six standard criteria. Even when some competing models (e.g., IXL, IE, IL, IW, IG, INH, and GIE, among others) yield numerically close values, such closeness further supports the efficiency of the IZL model, since a one-parameter distribution remains competitive with more parameterized alternatives while preserving inferential simplicity. Accordingly, the empirical findings confirm that the IZL distribution is not only theoretically tractable but also a practically useful competitor for modeling lifetime data exhibiting skewness, heavy tails, and nonmonotone reliability behavior.
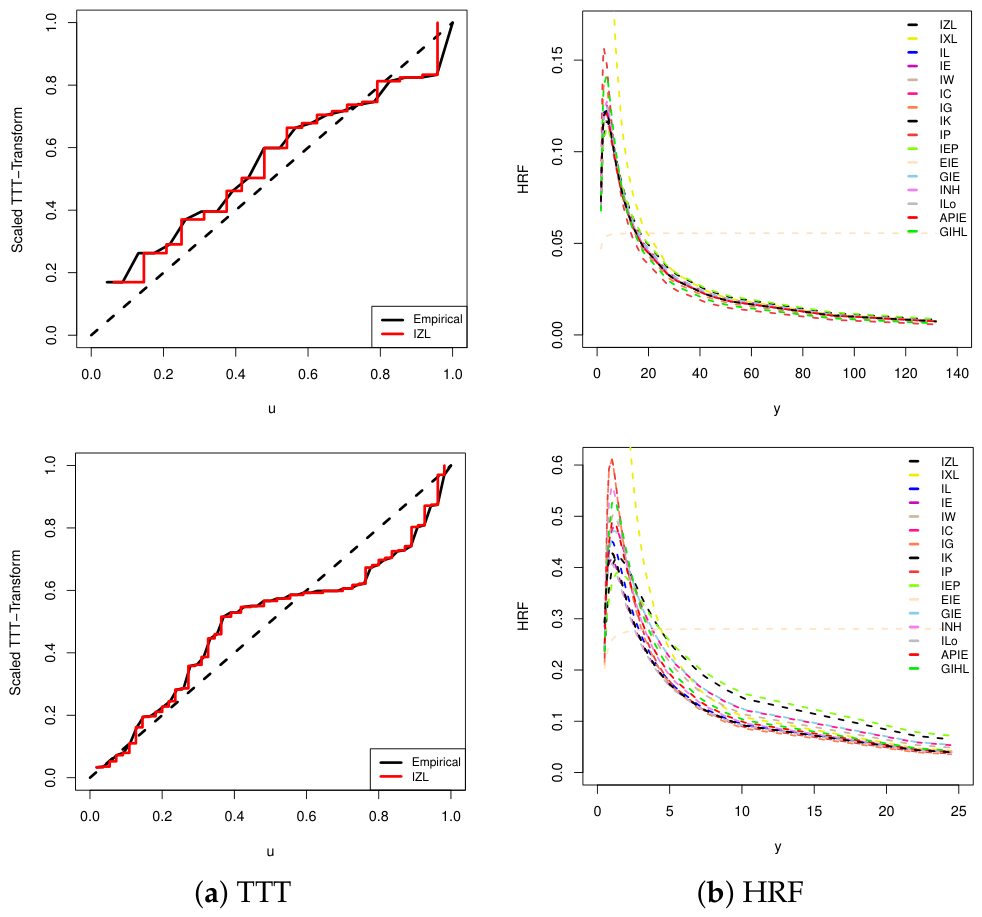
To further investigate the hazard-rate flexibility of the fitted models,
Figure 7 displays graphical comparisons of the fitted HRF lines for both UMC and ACT datasets. Specifically,
Figure 7a presents the empirical TTT transforms together with the fitted IZL TTT curves, while
Figure 7b shows the estimated HRFs of the IZL model and all competing distributions. The empirical TTT plots (shown in
Figure 7a) suggest non-constant failure mechanisms, supporting the need for flexible hazard-rate models. As shown in
Figure 7b, the fitted HRF curve of the IZL model follows the empirical pattern closely compared to other competitors, indicating that the proposed model captures the principal reliability structure of both UMC and ACT datasets. Moreover, the hazard-rate comparisons reveal that, although some competing models yield numerically similar information criteria, several of them differ substantially in early-time behavior, peak intensity, or tail decline. By contrast, the IZL model provides a stable and interpretable hazard pattern with competitive overall agreement. To sum up, the graphical findings (shown in
Figure 7a) are fully consistent with the formal goodness-of-fit results (listed in
Table 4) and provide additional evidence that the proposed IZL distribution constitutes an effective and parsimonious model for positively skewed lifetime data with complex reliability behavior.
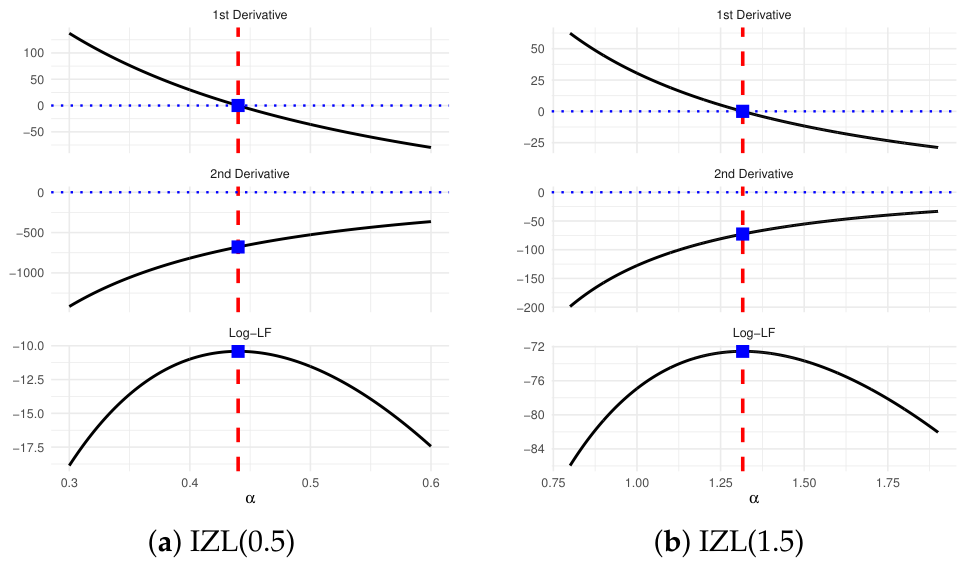
In parallel, the contour-style panels display the log-likelihood function and its first and second derivatives with respect to the parameter
, providing insight into the estimation process and curvature of the likelihood surface. For both datasets,
Figure 6a indicates that the offered values of
are valid and unique; subsequently, these values are used as initial guesses for any subsequent computations involving
. For both datasets,
Figure 6b indicates pronounced right-skewness and heavy-tailed behavior, justifying the use of flexible lifetime models rather than symmetric alternatives. Moreover, the zero-crossing of the first derivative together with the negative second derivative at the same point confirms the existence of a unique maximum of the log-likelihood, supporting the stability and reliability of the MLE for
.
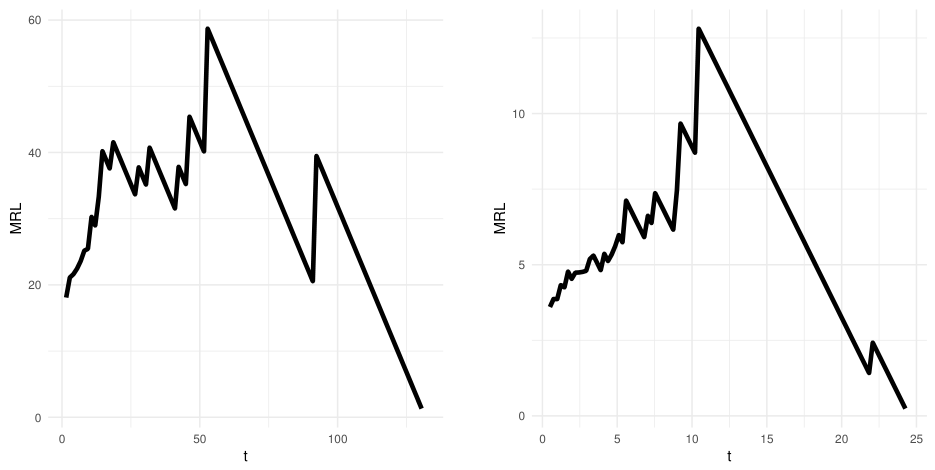
Empirical MRL analysis provides descriptive insight into the expected remaining lifetime of surviving units over the observed data range. Although the theoretical MRL in Theorem 4 is infinite due to the heavy-tailed structure of the IZL distribution, empirical MRL plots remain valuable practical tools for assessing residual-life behavior.
Figure 8 shows that both the UMC and ACT datasets exhibit an overall UBT-shaped MRL pattern, characterized by an initial increase, followed by a peak and subsequent decline. This observed behavior is broadly consistent with a non-monotonic residual-life structure, indicating that the IZL model can effectively capture flexible and realistic lifetime dynamics in practical applications.
Using the complete UMC and ACT datasets, three T2CS samples were generated for each dataset under different values of j. For each sample (), maximum likelihood and Bayesian estimates of the parameter , along with their corresponding standard errors, were computed. Additionally, 95% interval estimates of were obtained using asymptotic methods (ACI-NA and ACI-NL), bootstrap methods (Boot-p and Boot-t), and credible methods (BCI and HPD), with the corresponding interval widths recorded.
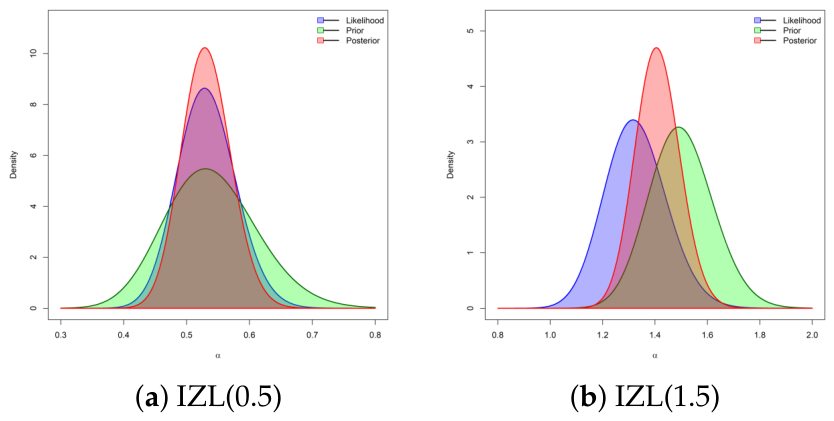
The selection of the hyperparameters in the gamma prior can be guided by several practical considerations. In applications where prior information is available, the parameters may be chosen to reflect expert knowledge about the scale of . Alternatively, an empirical Bayes approach can be adopted by estimating from the data, for example, via moment matching or marginal likelihood maximization. In the present study, since reliable prior information about for the UMC and ACT datasets is not available, weakly informative gamma priors (e.g., with small values of and ) are employed to ensure numerical stability while avoiding undue influence on the posterior inference. Thus, a gamma prior with hyperparameters (for ) was adopted to reflect near non-informative prior knowledge for the model. Posterior inference was performed using the M–H algorithm described in Algorithm 1, employing a burn-in period of 10,000 iterations and a total of 30,000 iterations.
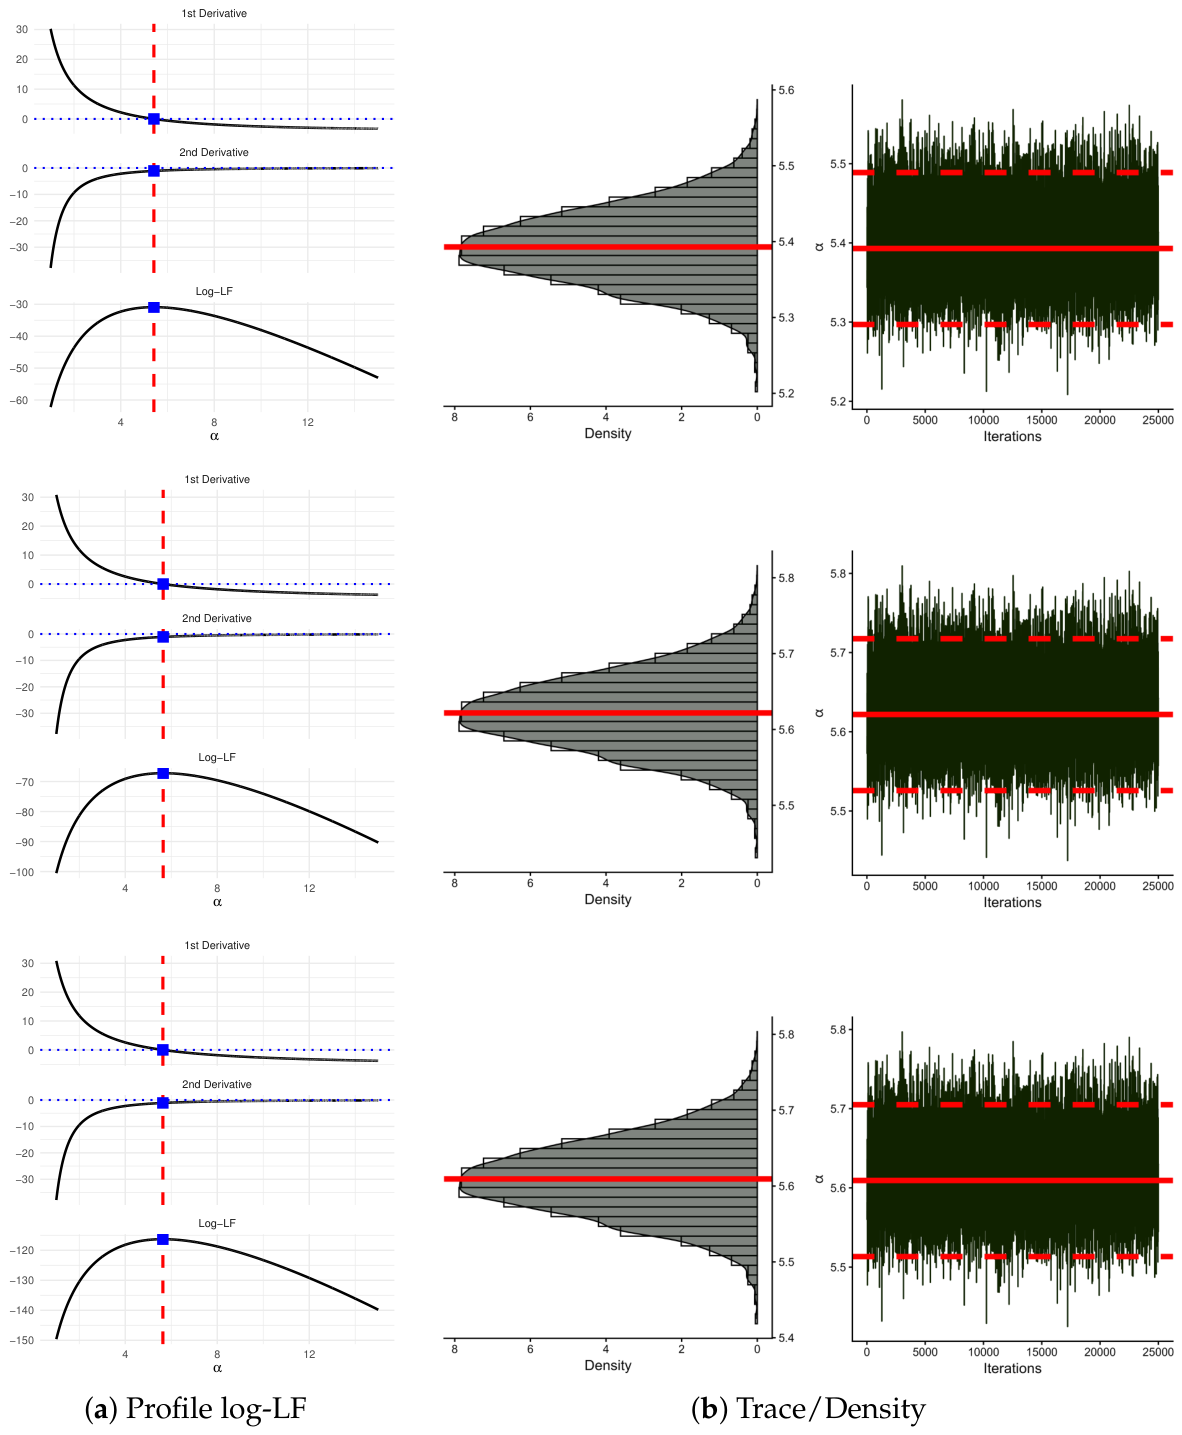
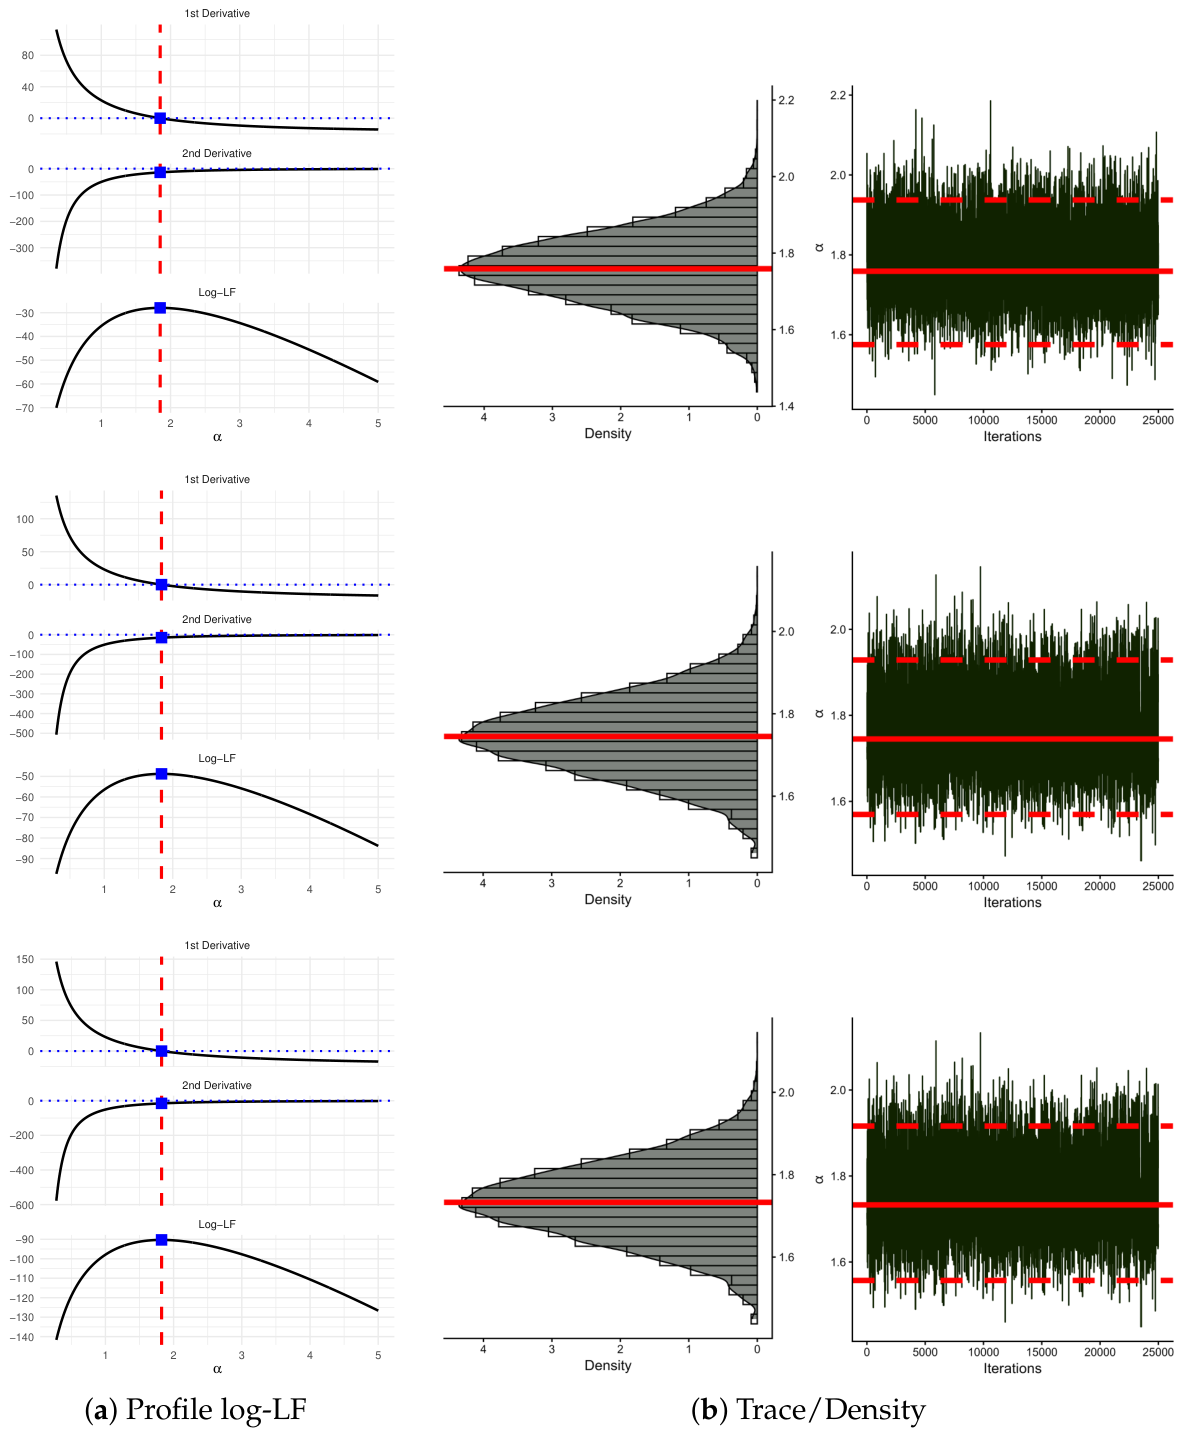
The existence and uniqueness of the MLE
were examined via the profile log-likelihood function and its first and second derivatives, as illustrated in
Figure 9 and
Figure 10. The resulting plots exhibit clear, well-defined maxima, indicating that the MLEs obtained from all samples
are unique for both datasets. The numerical estimates reported in
Table 5 align with these graphical findings and were therefore used as initial values in the Bayesian analysis. A brief summary of useful statistics for the retained 25,000 MCMC samples of
is provided in
Table 6. Furthermore,
Figure 9 and
Figure 10 present kernel density estimates and trace plots of the retained 25,000 MCMC samples of
, demonstrating good mixing and satisfactory convergence of the Markov chains. The approximate symmetry of the posterior samples further supports the adequacy of the selected burn-in period and confirms the reliability of the resulting Bayesian inference. These results demonstrate that both the frequentist and Bayesian methods provide reliable and consistent estimates of
across all censored samples created. In particular, the Bayesian approach, supported by MCMC diagnostics, exhibits robust convergence and efficient credible intervals, highlighting its suitability for inference under limited or censored data.
Overall, the results from the engineering and health sciences case studies demonstrate the versatility and practical value of the proposed IZL lifetime model for both complete and censored datasets. Specifically, the model effectively captures the dynamics of urinary metabolite concentrations in response to airborne contaminant exposure and accurately characterizes the active repair times of airborne communication transceivers, consistently outperforming fifteen widely used lifetime distributions and confirming its applicability to diverse real-world scenarios.
8. Conclusions and Future Perspectives
This study has introduced and systematically investigated a new one-parameter lifetime model, namely the IZL distribution, motivated by the need for parsimonious yet flexible alternatives to multi-parameter lifetime models commonly employed to capture non-monotone hazard behaviors. By leveraging an inversion mechanism, the proposed model successfully accommodates a UBT-shaped failure rate while maintaining analytical simplicity, interpretability, and computational feasibility. This balance between flexibility and parsimony represents a key contribution to contemporary distribution theory and reliability modeling. From a theoretical standpoint, the IZL distribution has been shown to possess rich structural properties. The density is strictly positive, unimodal, positively skewed, and heavy-tailed, while the hazard rate exhibits a unique unimodal shape with vanishing limits at both extremes. The derivation of an infinite-series expansion of the density provides a powerful analytical tool for studying tail behavior, moment existence, and approximation results. The explicit treatment of fractional moments, together with the formal justification for the non-existence of classical moments, highlights the importance of quantile-based and robustness-oriented summaries in heavy-tailed lifetime modeling.
Moreover, the availability of a closed-form quantile function through the Lambert W representation facilitates efficient simulation and supports both theoretical investigations and practical implementations. In terms of reliability analysis, the development of mean inactivity time and strong mean inactivity time functions enriches the interpretive capacity of the model, offering meaningful insights into system aging, downtime, and recovery dynamics. The explicit derivation of order statistics further broadens the applicability of the IZL distribution to extreme value analysis, stress–strength reliability, and system-level performance evaluation. Inferentially, the study provides a comprehensive framework for parameter estimation under Type-II censoring, encompassing likelihood-based and Bayesian methodologies. The existence and uniqueness of the maximum likelihood estimator ensure numerical stability, while Bayesian estimation via Markov chain Monte Carlo methods allows the incorporation of prior information and yields improved finite-sample performance. The comparative investigation of asymptotic, bootstrap, Bayesian credible, and HPD intervals demonstrates that Bayesian and HPD-based procedures are particularly effective in terms of estimation accuracy, interval length, and coverage probability, especially in censored and moderate-sample scenarios. The practical relevance of the proposed model has been convincingly demonstrated through applications to environmental health and communication engineering data. In both cases, the IZL distribution consistently outperforms a wide set of fifteen well-established inverted lifetime models across likelihood-based criteria, information measures, goodness-of-fit statistics, and graphical diagnostics. These empirical findings confirm that the proposed model is not only theoretically sound but also highly competitive in real-world applications involving skewness, heavy tails, and non-monotone failure dynamics.
8.1. Potential Research Directions
Several avenues for future research naturally arise from this work. First, the IZL framework may be extended to multi-parameter or regression-based versions by incorporating covariates, enabling its use in accelerated life testing, survival regression, and reliability modeling with explanatory variables. Second, the development of bivariate and multivariate extensions, possibly via copula constructions or shared frailty structures, would allow modeling of dependent lifetime data. Third, alternative censoring schemes, such as progressive, hybrid, or competing risk censoring, can be explored to further enhance the applicability of the model in complex experimental settings. Additionally, robust estimation techniques and goodness-of-fit tests specifically tailored to heavy-tailed inverted distributions merit further investigation.
8.2. Practical Recommendations
For practitioners in engineering and health sciences, the IZL distribution is recommended as a reliable and interpretable alternative when data exhibit early-life risk escalation, heavy tails, or unimodal hazard behavior. Bayesian inference with informative priors and HPD interval estimation is particularly advised in censored or small-to-moderate sample settings. Quantile-based summaries should be preferred over moment-based measures when describing central tendency and dispersion.
In summary, the proposed IZL distribution constitutes a meaningful contribution to modern lifetime modeling by unifying theoretical rigor, inferential robustness, and practical effectiveness within a parsimonious one-parameter framework. It opens several promising directions for future research while offering an immediately applicable tool for modeling complex reliability phenomena.
Ultimately, future research may investigate the applicability of the proposed IZL distribution beyond the two analyzed datasets, since its usefulness is not restricted to communication engineering and environmental health, but can be naturally extended to other domains such as finance, hydrology, insurance risk, biomedical survival studies, and industrial reliability data.