Article

Interpolating Missing Spatial Data Using Graph Laplacian Eigenbasis

1
Graduate School of Humanities and Social Sciences, Hiroshima University, 1-2-1 Kagamiyama, Higashihiroshima 739-8525, Japan
2
Faculty of Economics, Kansai University, 3-3-35 Yamate, Suita 564-8680, Japan
*
Author to whom correspondence should be addressed.
Mathematics 2026, 14(9), 1435; https://doi.org/10.3390/math14091435
Submission received: 3 March 2026 / Revised: 3 April 2026 / Accepted: 19 April 2026 / Published: 24 April 2026
(This article belongs to the Special Issue Graph Theory and Applications, 3rd Edition)

Abstract

This paper addresses the problem of interpolating missing spatial data at the vertices of a connected undirected simple graph. We show that, by exploiting the eigenbasis of the graph Laplacian, all missing values can be reconstructed even from a single observation. This work establishes a novel connection between spatial statistics and spectral graph theory.

1. Introduction

In this paper, we study the problem of recovering missing spatial data at the vertices of an undirected graph. We assume that the graph is connected. Furthermore, it is simple; that is, it has no self-loops or multiple edges. We demonstrate that by leveraging the structure of the graph, all missing values can be reconstructed even when only a single observation is available. Here, exploiting the graph structure specifically means utilizing the eigenbasis of the graph Laplacian. As shown in Yamada (2023) [1], the graph Laplacian eigenvectors can be ordered according to Geary’s c (Geary, 1954 [2]; Cliff and Ord, 1969, 1970, 1973, 1981 [3,4,5,6]), one of the most widely used measures of spatial autocorrelation, which is a spatial extension of the time series autocorrelation measure developed by von Neumann (1941) [7]. This property is central to our approach. In this paper, we establish a novel connection between spatial statistics and spectral graph theory.
We describe the motivation behind the present study. The Hodrick–Prescott (HP) filter (Hodrick and Prescott, 1997 [8]) is a standard method for estimating time trend in econometrics. However, it cannot be directly applied when missing values are present. To overcome this limitation, Yamada (2022) [9] proposed a generalized version of the HP filter, which allows the estimation of the time trend and the simultaneous interpolation of missing values. A key observation is that a time series can be interpreted as data at the vertices of a path graph. This motivates the spatial extension of the method proposed by Yamada (2022) [9], enabling the interpolation of missing spatial values.
The remainder of this paper is organized as follows. Section 2 presents the preliminaries required for the main result. Section 3 states the main result. In particular, it introduces a method for reconstructing missing spatial data using the graph structure. Section 4 provides the proof of the main result. Section 5 illustrates the application of the proposed method to real data. Section 6 concludes the paper. Appendix A provides an additional proof.

2. Preliminaries

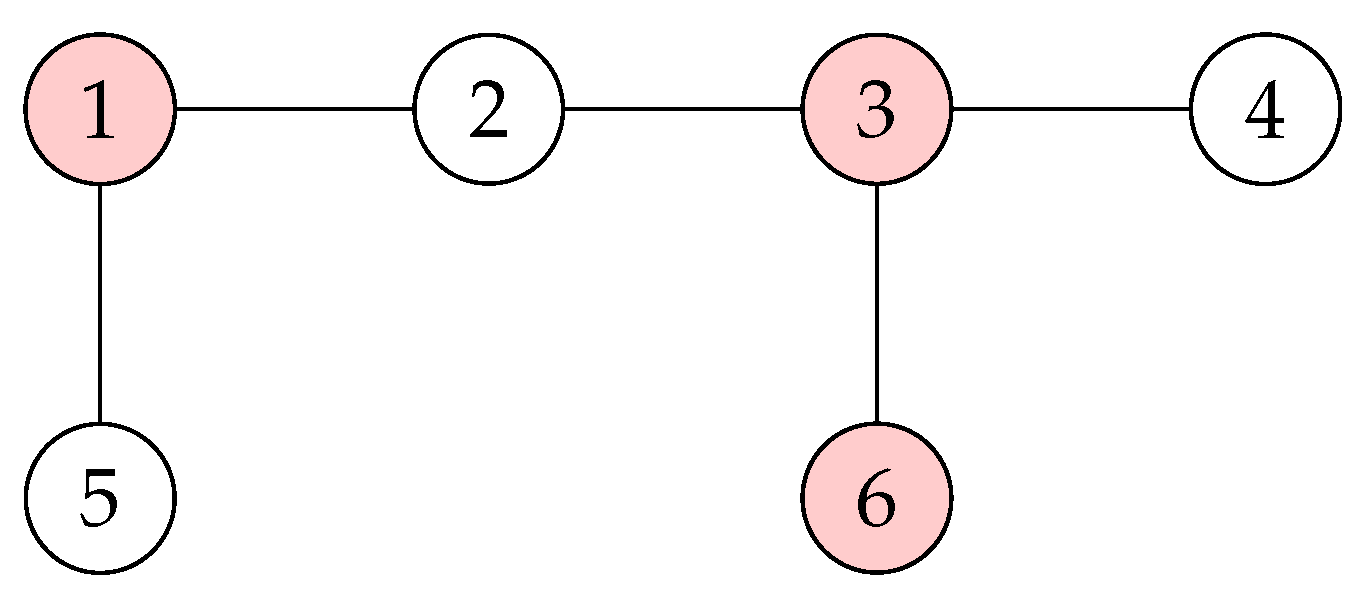
Consider an undirected graph G = ( V , E ) with no self-loops or multiple edges, where V = { 1 , , n } . We assume that n = | V | 2 , | E | 1 , and G is connected. Let A = { i 1 , , i m } and B = { i m + 1 , , i n } , where { i 1 , , i n } = V and 1 m < n . Then A and B are subsets of the vertex set V such that both A and B are nonempty, A B = V , and A B = . Therefore, { A , B } is a partition of V. Let y i denote the value of y at vertex i for i = 1 , , n . In this paper, we consider the setting in which y i is missing for i B , while y i is observed for i A . We refer to the sets A and B as the observed set and the unobserved set, respectively. Figure 1 shows a connected undirected graph with six vertices, where the values at the colored vertices are missing. Accordingly, in this graph, the observed set is A = { 2 , 4 , 5 } and the unobserved set is B = { 1 , 3 , 6 } .
Let y = [ y 1 , , y n ] , y a = [ y i 1 , , y i m ] , and y b = [ y i m + 1 , , y i n ] . Let ι n be the n-dimensional column vector of ones, I n = [ e 1 , , e n ] be the identity matrix of order n, and 0 denote a zero vector or matrix of appropriate dimension. Let S a = [ e i 1 , , e i m ] and S b = [ e i m + 1 , , e i n ] . Then we have y a = S a y and y b = S b y . Since m is an integer such that 1 m < n , both S a and S b are nonzero matrices. Moreover, since [ S a , S b ] is an n × n permutation matrix, we have
[ S a , S b ] S a S b = S a S a + S b S b = I n ,
from which y can be decomposed as
y = S a y a + S b y b .
Note that S a y a coincides with y on the observed components and is zero on the unobserved components.
Let W be an n × n matrix whose ( i , j ) entry is w i , j , where
w i , j > 0 if { i , j } E , w i , j = 0 if { i , j } E ,
for i , j = 1 , , n . Since G is an undirected graph with no self-loops or multiple edges, W is a symmetric hollow matrix, i.e., w i , j = w j , i and w i , i = 0 . It is often assumed that w i , j = 1 whenever w i , j > 0 , in which case W is a binary matrix. Let D = diag ( d 1 , , d n ) , where d i = j = 1 n w i , j for i = 1 , , n . Then the graph Laplacian L corresponding to the graph G can be defined using W and D as
L = D W .
See, e.g., Bapat (2014) [10], Estrada and Knight (2015) [11], and Gallier (2016) [12]. The matrices W and D are referred to as the (weighted) adjacency matrix and the degree matrix of the graph G, respectively.
As an example, we present the graph Laplacian of the graph shown in Figure 1, assuming that the adjacency matrix W is binary. Since the edge set of the graph is
E = { { 1 , 2 } , { 1 , 5 } , { 2 , 3 } , { 3 , 4 } , { 3 , 6 } } ,
the corresponding graph Laplacian L is given by
L = 2 0 0 0 0 0 0 2 0 0 0 0 0 0 3 0 0 0 0 0 0 1 0 0 0 0 0 0 1 0 0 0 0 0 0 1 0 1 0 0 1 0 1 0 1 0 0 0 0 1 0 1 0 1 0 0 1 0 0 0 1 0 0 0 0 0 0 0 1 0 0 0
= 2 1 0 0 1 0 1 2 1 0 0 0 0 1 3 1 0 1 0 0 1 1 0 0 1 0 0 0 1 0 0 0 1 0 0 1 .    
For example, the ( 1 , 2 ) and ( 2 , 1 ) entries of L are −1 since vertices 1 and 2 are adjacent. Similarly, the ( 2 , 2 ) entry is 2 since vertex 2 is adjacent to two other vertices, namely 1 and 3.
We denote the eigenvalues of L by q 1 , , q n in ascending order. Since the graph G is connected, L has rank n 1 . Moreover, L is positive semidefinite (see, e.g., Yamada, 2021 [13]). Thus,
q 1 = 0 , 0 < q 2 q n .
Let
L = P Q P ,
be a spectral decomposition of a real symmetric matrix L , where Q = diag ( q 1 , , q n ) and P = [ p 1 , , p n ] . Then P is an n × n orthogonal matrix, and hence the column vectors of P , { p 1 , , p n } , form an orthonormal basis of R n . In addition, since L ι n = 0 , we may take p 1 = 1 n ι n , and hence the remaining vectors p i for i = 2 , , n lie in the orthogonal complement of S ( ι n ) . Here, S ( ι n ) denotes the column space of ι n . Moreover, given that p i L p i = q i for i = 1 , , n , it follows from (7) that
p 1 L p 1 = 0 , 0 < p 2 L p 2 p n L p n .
Let c ( η ) denote the Geary’s c of an n-dimensional column vector η = [ η 1 , , η n ] R n S ( ι n ) associated with the graph G. Geary’s c is a widely used measure of spatial autocorrelation. As shown in Yamada (2021) [13], it is expressed in terms of η L η as
c ( η ) = n 1 i = 1 n j = 1 n w i , j 1 2 i = 1 n j = 1 n w i , j ( η i η j ) 2 i = 1 n ( η i η ¯ ) 2 = n 1 ι n W ι n η L η η M n η ,
where η ¯ = 1 n i = 1 n η i and M n = I n ι n ( ι n ι n ) 1 ι n .
Since p i for i = 2 , , n lie in the orthogonal complement of S ( ι n ) and satisfy p i   = 1 , it follows that p i M n p i = p i 2 = 1 for i = 2 , , n . Thus, Geary’s c for p i , c ( p i ) , is given by
c ( p i ) = n 1 ι n W ι n p i L p i ,
for i = 2 , , n . Therefore, it follows from (9) that
0 < c ( p 2 ) c ( p n ) .
Note that c ( p 1 ) is not defined, since p 1 M n p 1 = 0 .
Equation (12) is crucial for this study. Since Geary’s c takes non-negative values and smaller values indicate stronger positive spatial autocorrelation, the inequalities in (12) imply that, for example, p i exhibits stronger positive spatial autocorrelation in the sense of Geary’s c than p i + 1 for i = 2 , , n 1 .

3. Interpolating Missing Spatial Data

Motivated by the monotonicity condition on the graph Laplacian eigenvectors in (12), we consider the following minimization problem for reconstructing y b R n m from y a R m :
min y b R n m , θ 1 , , θ n R ( S a y a + S b y b ) ( θ 1 p 1 + θ 2 p 2 + + θ n p n ) 2 ,
s . t . q 1 θ 1 2 + + q n θ n 2 κ ,
where κ is a positive constant. Note that since q 1 = 0 , q 1 θ 1 2 + + q n θ n 2 in the constraint can equivalently be written as q 2 θ 2 2 + + q n θ n 2 . Given the ordering condition in (7), the weight associated with θ i + 1 is greater than or equal to that associated with θ i for i = 2 , , n 1 . Consequently, under the monotonicity condition on the graph Laplacian eigenvectors in (12), this weighting structure allows for the reconstruction of y b .
Let θ = [ θ 1 , , θ n ] . Then the above constrained minimization problem can be written in matrix form as
min y b R n m , θ R n ( S a y a + S b y b ) P θ 2 ,
s . t . θ Q θ κ .
Recall that P = [ p 1 , , p n ] and Q = diag ( q 1 , , q n ) . The constrained minimization problem (15) and (16) is equivalent to the following penalized least squares problem:
min y b R n m , θ R n f ( y b , θ ) = ( S a y a + S b y b ) P θ 2 + λ θ Q θ ,
where λ is a non-negative smoothing parameter. More precisely, for any κ , there exists a λ that yields an equivalent solution (see, e.g., Beck, 2014 [14]). The two parameters, κ and λ , are inversely related. For example, κ 0 + corresponds to λ .
Incidentally, the above penalized least squares problem is similar to that considered in Yamada (2022) [9]. This is because, by letting x = P θ , (17) can be rewritten as a graph Laplacian-penalized least squares problem:
min y b R n m , x R n g ( y b , x ) = ( S a y a + S b y b ) x 2 + λ x L x .
Note that this formulation is equivalent to the spatial smoothing method considered in Yamada (2024) [15] when m = n , i.e., when there are no missing values, although this case is not considered in the present paper.
Concerning the minimization problem in (17), the following result holds.
Theorem 1.
If m 1 and λ > 0 , then there exists a unique global minimizer ( y ^ b , θ ^ ) such that
f ( y b , θ ) f ( y ^ b , θ ^ ) , y b R n m , θ R n ,
with equality if and only if y b = y ^ b and θ = θ ^ . Moreover, the minimizers are explicitly given by
y ^ b = S b P θ ^ ,
θ ^ = P ( S a S a + λ L ) 1 S a y a .
Proof. 
A proof is given in Section 4.    □
Equation (20) shows that y b can be interpolated using the graph Laplacian eigenbasis { p 1 , , p n } as
y ^ b = S b ( θ ^ 1 p 1 + + θ ^ n p n ) ,
where θ ^ i denotes the i-th entry of θ ^ for i = 1 , , n . Furthermore, by substituting (21) into (20), we obtain the following alternative representation:
y ^ b = S b ( S a S a + λ L ) 1 S a y a ,
which explicitly shows how y ^ b is reconstructed from the observed data y a . Recall that S a y a coincides with y on the observed components and is zero on the unobserved components.
Finally, we make three remarks on the above result. First, S a S a + λ L is nonsingular because the following lemma holds.
Lemma 1.
If m 1 , then S a S a + λ L is positive definite for any positive λ.
Proof. 
First, consider the case where ξ S ( p 1 ) { 0 } . In this case, ξ can be expressed as ξ = p 1 α for some α 0 . Since S a p 1 = S a ( 1 n ι n ) = 1 n ι m and L ξ = L p 1 α = α n L ι n = 0 , we obtain
ξ ( S a S a + λ L ) ξ = α 2 S a p 1 2 = α 2 m n > 0 ,
if m 1 .
Next, consider the case where ξ R n S ( p 1 ) . In this case, ξ can be expressed as ξ = p 1 α + P 2 β for some α and some β 0 , where P 2 = [ p 2 , , p n ] . Again, since L p 1 = 0 , it follows that
ξ L ξ = ( p 1 α + P 2 β ) L ( p 1 α + P 2 β ) = β P 2 P Q P P 2 β = β Q 2 β > 0 ,
where Q 2 = diag ( q 2 , , q n ) . The last inequality follows since Q 2 is positive definite. Therefore, for any λ > 0 , it follows from (25) that
ξ ( S a S a + λ L ) ξ = S a ξ 2 + λ ξ L ξ > 0 .
Combining the above cases, we conclude that for any ξ R n { 0 } , ξ ( S a S a + λ L ) ξ > 0 .    □
Accordingly, we note that our main result in (22) requires the condition m 1 , i.e., at least one data point must be observed.
Second, we show that θ ^ can be regarded as the solution of a generalized ridge regression (Hoerl and Kennard, 1970 [16]). Let U = S a P R m × n . Then it follows from (21) that
θ ^ = P ( S a S a + λ L ) 1 S a y a = P ( P P S a S a P P + λ P Q P ) 1 S a y a = ( P S a S a P + λ Q ) 1 P S a y a = ( U U + λ Q ) 1 U y a ,
which is the solution of the following generalized ridge regression:
min θ R n y a U θ 2 + λ θ Q θ .
We note that, even though U is an m × n matrix with m < n , U U + λ Q is positive definite. This follows from the fact that U U + λ Q is similar to S a S a + λ L as
P ( S a S a + λ L ) P = P S a S a P + λ P L P = U U + λ Q .
Third, we provide insights into how y ^ b in (20) depends on the smoothing parameter λ . In particular, we have
y ^ b y ¯ a ι n m , ( λ ) ,
where y ¯ a denotes the mean of the entries of y a , i.e., y ¯ a = 1 m h = 1 m y i h . A proof of (30) is given in Appendix A. Furthermore, from Lemma 1, S a S a + λ L is positive definite for any λ > 0 when m 1 . However, it becomes ill-conditioned as λ 0 + since S a S a is rank-deficient. Therefore, λ should not be chosen too small.

4. Proof of Theorem 1

In this section, we provide a proof of Theorem 1.
Proof of Theorem 1.
Let R = [ P , S b ] R n × ( 2 n m ) , ϕ = [ θ , y b ] R 2 n m , and Ω = diag ( Q , 0 ) R ( 2 n m ) × ( 2 n m ) . Then since
( S a y a + S b y b ) P θ = S a y a [ P , S b ] θ y b = S a y a R ϕ , θ Q θ = [ θ , y b ] Q 0 0 0 θ y b = ϕ Ω ϕ ,
the objective function in (17) can be rewritten as
f ( ϕ ) =   S a y a R ϕ 2 + λ ϕ Ω ϕ = ϕ ( R R + λ Ω ) ϕ 2 ( S a y a ) R ϕ + ( S a y a ) ( S a y a ) .
   □
Accordingly, the Hessian matrix of f ( ϕ ) is
H = 2 ( R R + λ Ω ) = 2 P S b [ P , S b ] + λ Q 0 0 0 = 2 I n + λ Q P S b S b P I n m .
Lemma 2.
If m 1 , then H is positive definite for any positive λ.
Proof. 
Since both R R and Ω are positive semidefinite and λ > 0 , H is positive semidefinite. Then H is positive definite if | H | > 0 . Since I n S b S b = S a S a and P is orthogonal, we have
1 2 H = I n + λ Q P S b S b P I n m = | I n + λ Q P S b S b P | = | P ( I n + λ P Q P S b S b ) P | = | P | | S a S a + λ L | | P | = | S a S a + λ L | > 0 ,
where the last inequality follows from Lemma 1. (Note that I n + λ Q P S b S b P is the Schur complement of I n m in 1 2 H .) Therefore, | H | > 0 . Since H is positive semidefinite, this implies that H is positive definite.
Let ϕ ^ be the column vector such that f ( ϕ ^ ) ϕ = 0 . Then since f ( ϕ ) is quadratic and its Hessian matrix is positive definite from Lemma 2, it follows that
f ( ϕ ) f ( ϕ ^ ) = 1 2 ( ϕ ϕ ^ ) H ( ϕ ϕ ^ ) > 0 , ϕ R 2 n m { ϕ ^ } .
Hence, ϕ ^ is the unique global minimizer of f ( ϕ ) .
Here, since f ( ϕ ) ϕ = 2 ( R R + λ Ω ) ϕ 2 R S a y a , the minimizer ϕ ^ satisfies
( R R + λ Ω ) ϕ ^ = R S a y a .
Then given that S b S a y a = 0 , (31) can be written in terms of θ ^ and y ^ b as
I n + λ Q P S b S b P I n m θ ^ y ^ b = P S a y a 0 ,
which yields the following system of equations
( I n + λ Q ) θ ^ P S b y ^ b = P S a y a ,
y ^ b = S b P θ ^ .
Substituting (33) into (32), we obtain
( I n + λ Q ) θ ^ P S b y ^ b = ( I n + λ Q ) θ ^ P S b S b P θ ^ = ( I n + λ Q P S b S b P ) θ ^ = P ( I n + λ L S b S b ) P θ ^ = P ( S a S a + λ L ) P θ ^ .
Accordingly, (32) becomes
P ( S a S a + λ L ) P θ ^ = P S a y a .
Since ( S a S a + λ L ) in (34) is nonsingular from Lemma 1, (21) follows immediately.   □

5. Illustration Using Real Data

We demonstrate the practical utility of the proposed graph-based interpolation method using the widely used meuse dataset available in the R sp package. We focus on the elevation variable, which exhibits strong positive spatial autocorrelation. We randomly selected 30% of the data to be treated as missing, leaving 70% of the observations available (i.e., m = 0.7 n ). Since n = 155 , this yields | A | = m = 108 observed and | B | = n m = 47 missing values. We generated a neighbor list from the point coordinates using tri2nb function in the R spdep package, and then converted it to an adjacency matrix for subsequent spatial analysis.
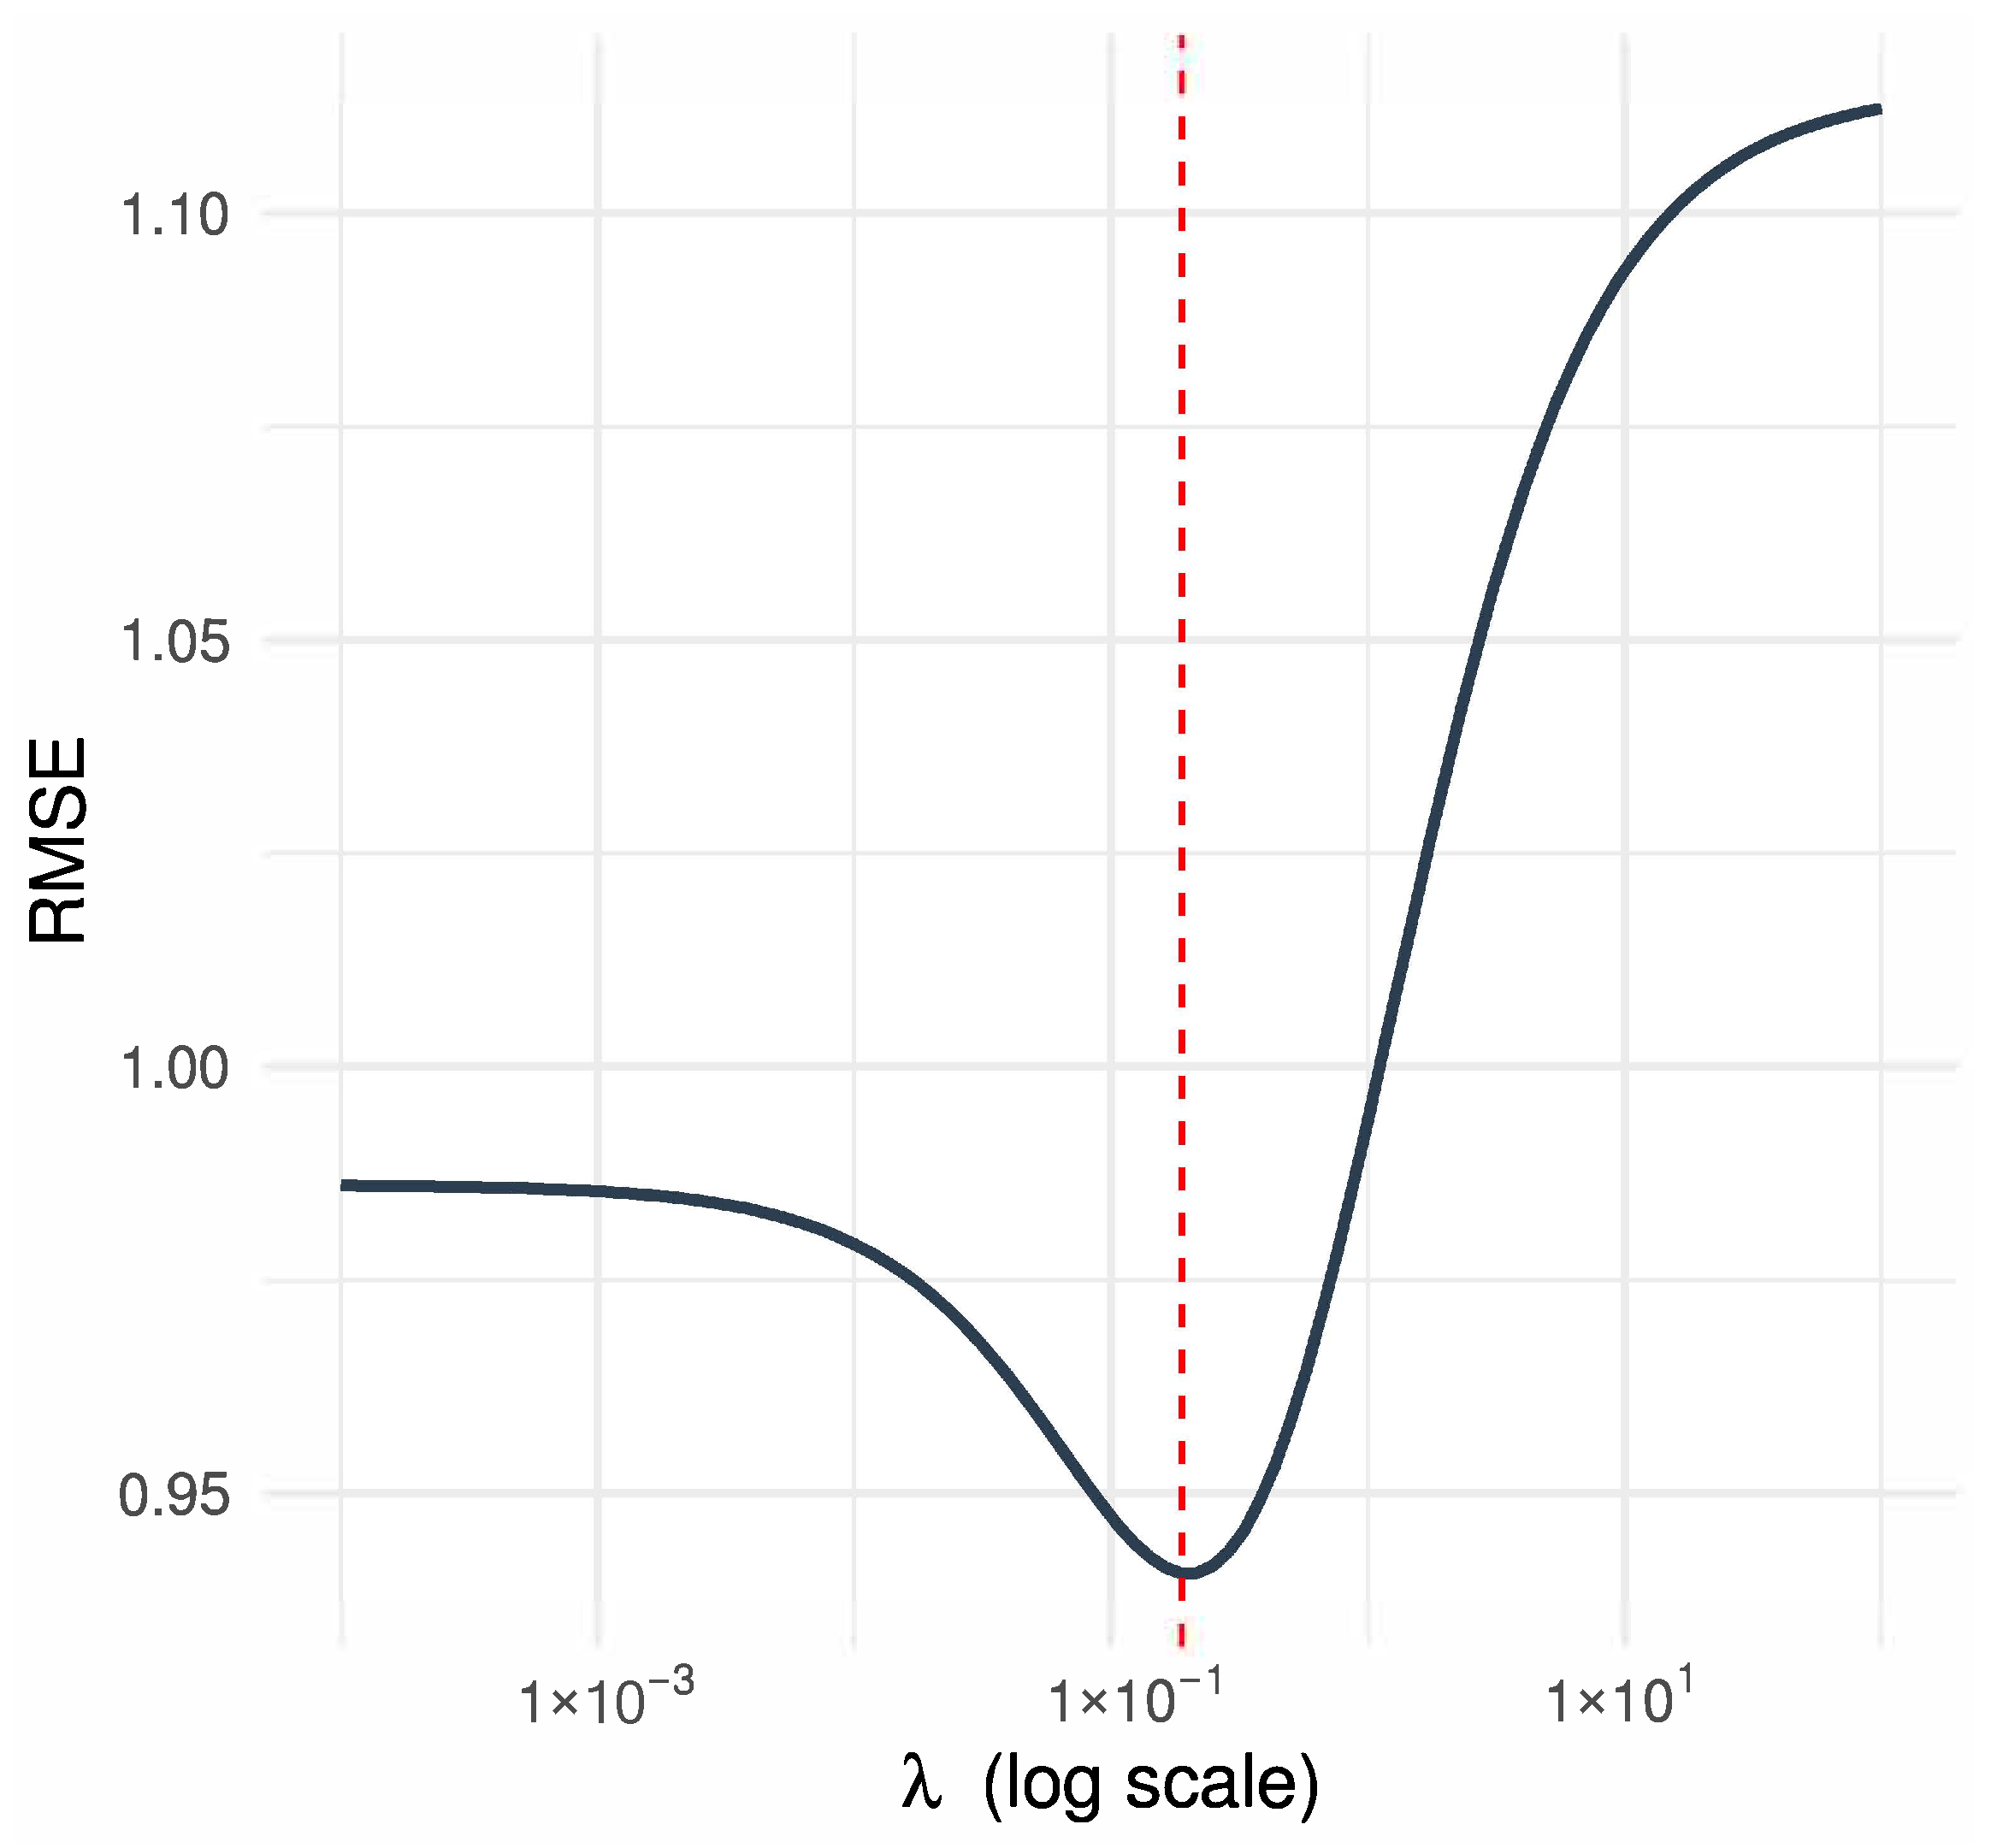
To apply our graph-based interpolation method, we need to specify the smoothing parameter λ . For this purpose, we used a 5-fold spatial block cross-validation procedure (Roberts et al., 2017 [17]). Specifically, we partitioned the observations into 5 spatial blocks based on their coordinates using K-means clustering (MacQueen, 1967 [18]). The optimal value of λ was then selected from 100 logarithmically spaced points between 10 4 and 10 2 . As shown in Figure 2, the selected value, indicated by a red dashed line, is λ = 0.1874 .
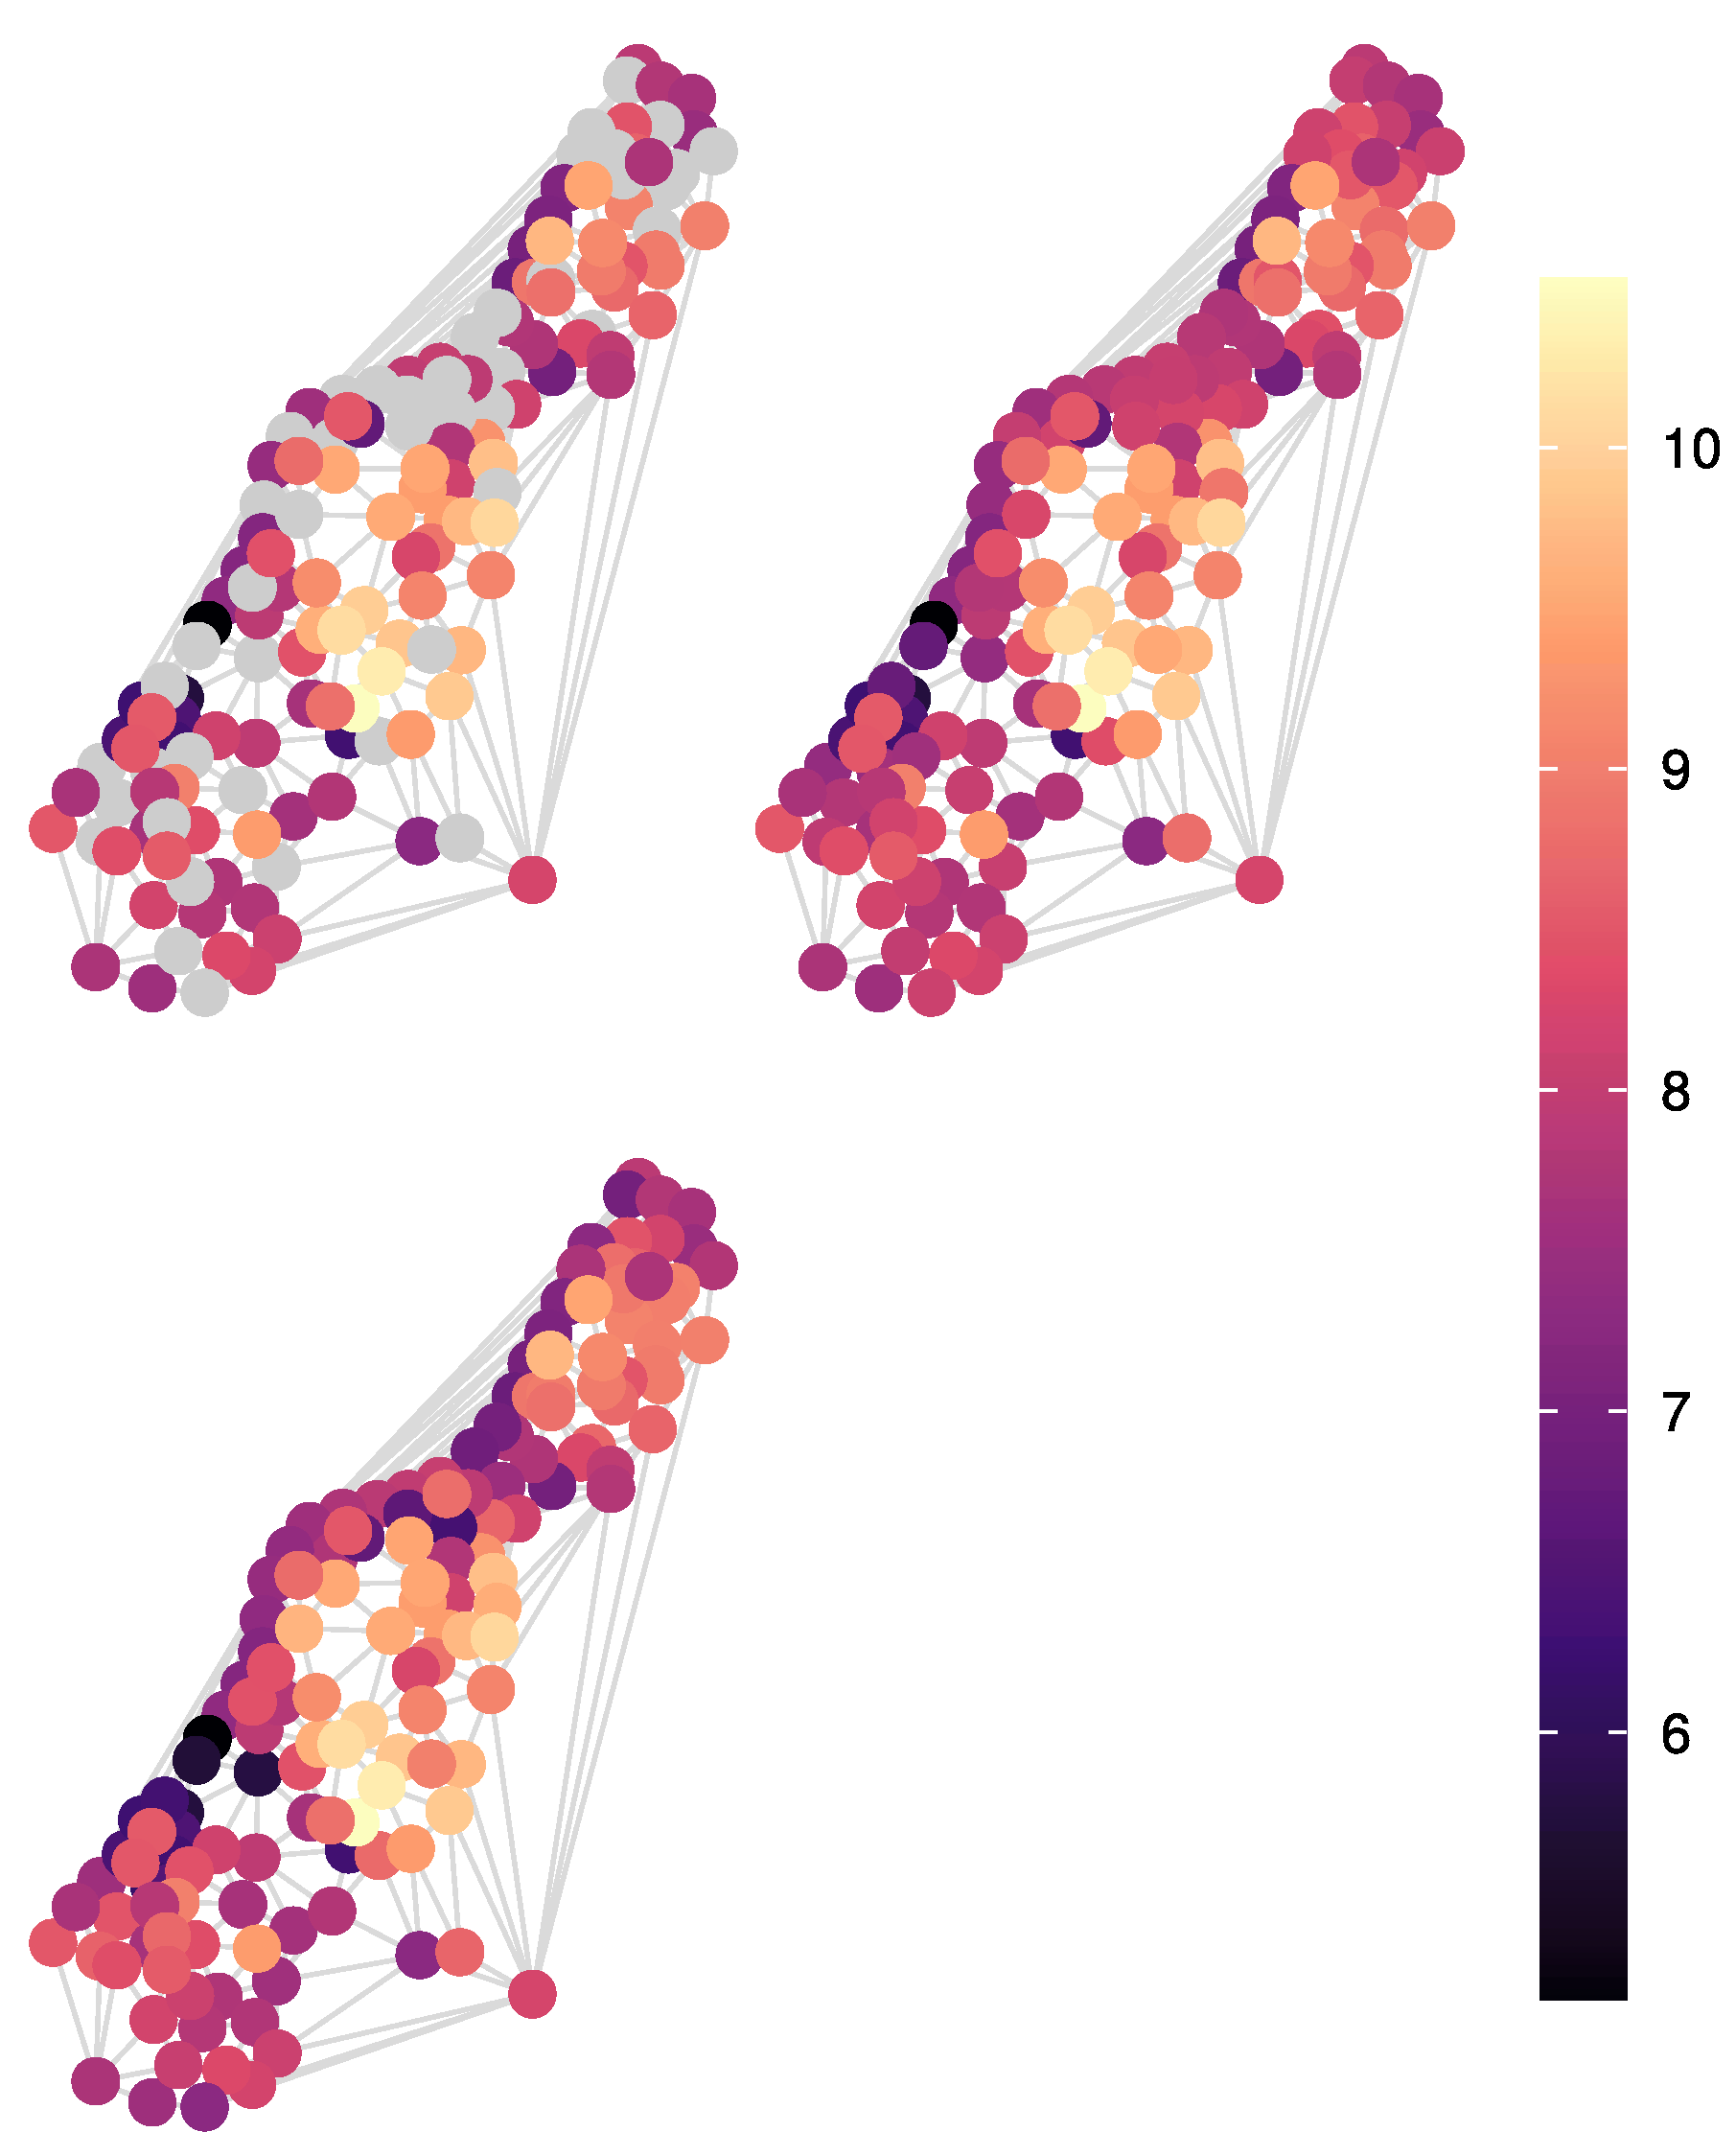
Figure 3 illustrates the performance of the proposed graph-based interpolation method. It shows the observed data with 30% of the values randomly removed (top left), the imputed data obtained using the proposed graph-based interpolation method (top right), and the original complete data (bottom left). The reconstructed values closely match the true elevations, indicating that the method provides highly accurate interpolations for spatially autocorrelated missing data.
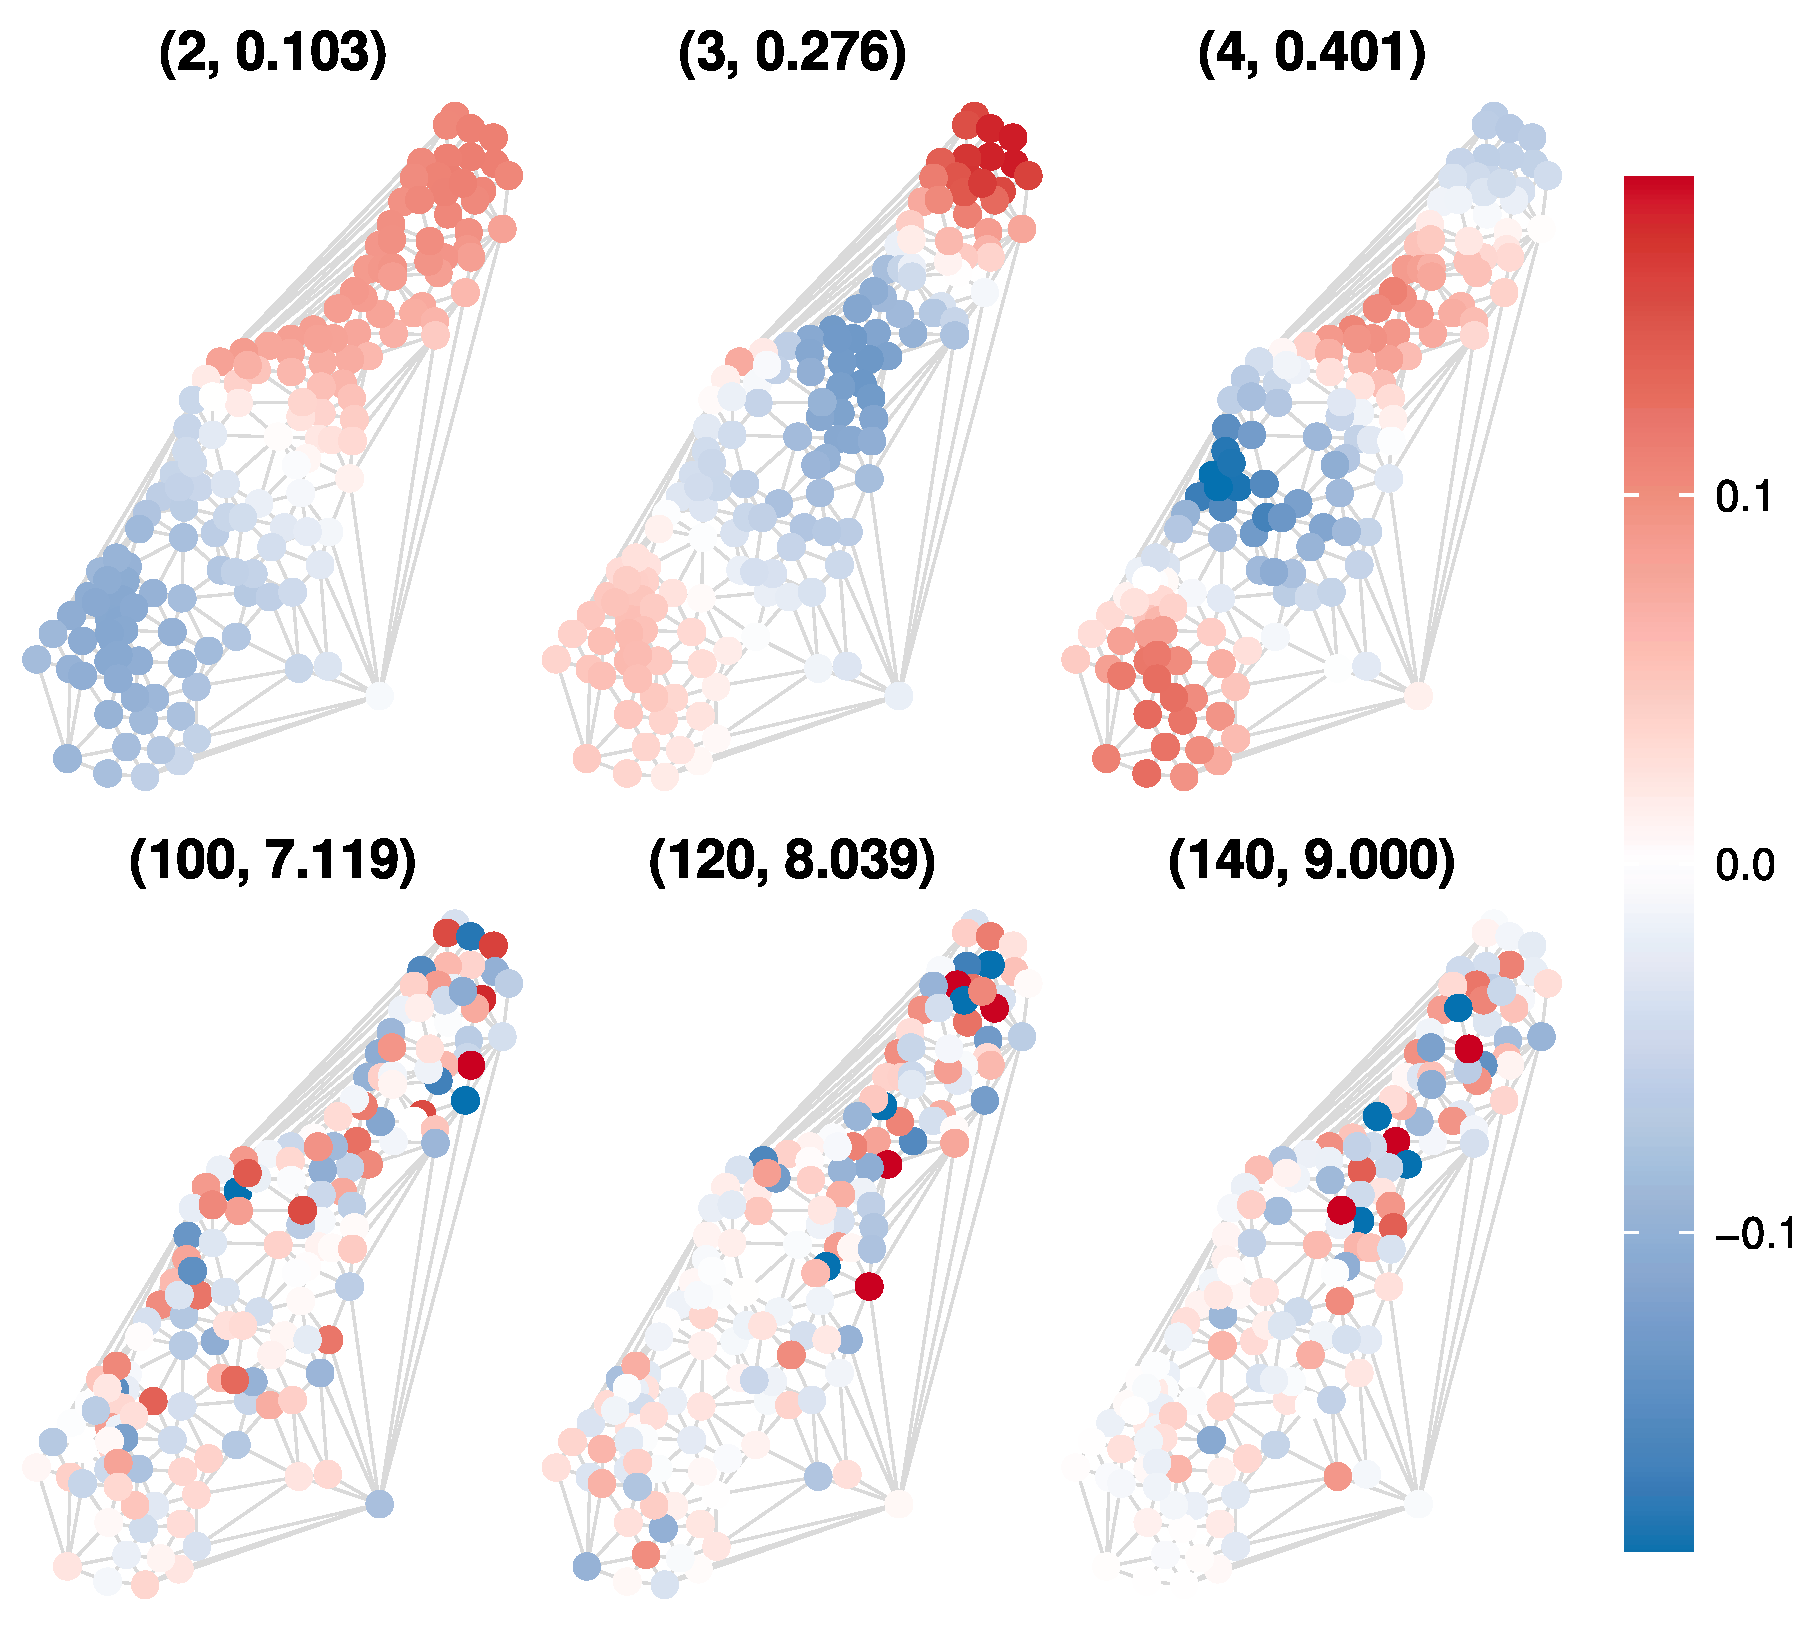
Finally, for reference, we present plots of several graph Laplacian eigenvectors. Figure 4 shows p i for i = 2 , 3 , 4 , 100 , 120 , 140 . In each panel, the first element of the ordered pair denotes the index i, and the second gives the value of p i L p i . For instance, the top-left panel displays p 2 with p 2 L p 2 = 0.103 . From this figure, it is clear that spatial autocorrelation is high when i is small, whereas it becomes low when i is large. In fact, as i increases, p i L p i strictly increases. This figure provides a visualization of the inequalities in (9) and (12).

6. Concluding Remarks

In this paper, we established a novel connection between spatial statistics and spectral graph theory. By exploiting the graph Laplacian eigenbasis that reflects the underlying graph structure, we showed that all missing values can be reconstructed, even from a single observation. This is made possible by the fact that the eigenvectors of the graph Laplacian can be ordered according to their spatial autocorrelation measured by Geary’s c. The main result of this study is presented in Theorem 1. We also provided an empirical illustration of our method, showing its practical effectiveness. These results highlight the usefulness of the graph Laplacian eigenbasis in spatial statistics and suggest promising directions for future developments.
Finally, although we derived the predictor y ^ b for the missing-value vector y b in Theorem 1, the detailed properties of this predictor have not yet been investigated and are left for future work. Additionally, clarifying the advantages and disadvantages of the method proposed in this paper compared to other approaches, such as kriging, will be an important topic for future research.


Author Contributions

Conceptualization, H.Y.; Methodology, H.Y.; Writing—original draft, Z.J.; Writing—review editing, Z.J. and H.Y.; Supervision, H.Y.; Project administration, H.Y.; Funding acquisition, Z.J. and H.Y. All authors have read and agreed to the published version of the manuscript.

Funding

Zihan Jin gratefully acknowledges financial support from the Japan Science and Technology Agency (JST) SPRING Program (Grant No. JPMJSP2132), and Hiroshi Yamada gratefully acknowledges financial support from the Japan Society for the Promotion of Science (JSPS) KAKENHI (Grant No. 23K01377).

Data Availability Statement

No new data were created or analyzed in this study.

Acknowledgments

We would like to thank the three anonymous referees for their insightful comments and helpful suggestions. Most of this work was carried out while Hiroshi Yamada was at Hiroshima University, and he would like to express his gratitude to the university for its support.

Conflicts of Interest

The authors declare no conflicts of interest.

Appendix A

In this section, we provide an additional proof.
Proof of (30).
From (27), we have
( U U + λ Q ) θ ^ = U y a ,
which can be written as
u 1 u 1 θ ^ 1 + u 1 U 2 θ ^ 2 = u 1 y a ,
U 2 u 1 θ ^ 1 + ( U 2 U 2 + λ Q 2 ) θ ^ 2 = U 2 y a ,
where θ ^ = [ θ ^ 1 , θ ^ 2 ] R n with θ ^ 1 R , and U = [ u 1 , U 2 ] R m × n with u 1 R m . Solving (A1) and (A2) yields
θ ^ 1 = ( u 1 u 1 ) 1 u 1 ( y a U 2 θ ^ 2 ) ,
θ ^ 2 = ( U 2 M m U 2 + λ Q 2 ) 1 U 2 M m y a ,
where M m = I m u 1 ( u 1 u 1 ) 1 u 1 . Let Q 2 1 2 = diag ( q 2 , , q n ) . Denote a spectral decomposition of a real symmetric matrix Q 2 1 2 U 2 M m U 2 Q 2 1 2 by Π Γ Π . Then,
( U 2 M m U 2 + λ Q 2 ) 1 = Q 2 1 2 ( Q 2 1 2 U 2 M m U 2 Q 2 1 2 + λ I n 1 ) 1 Q 2 1 2 = Q 2 1 2 ( Π Γ Π + λ Π Π ) 1 Q 2 1 2 = Q 2 1 2 Π ( Γ + λ I n 1 ) 1 Π Q 2 1 2 0 , ( λ ) ,
from which we have θ ^ 2 0 as λ . Thus, as λ , it follows from (A3) that θ ^ 1 ( u 1 u 1 ) 1 u 1 y a . Therefore, we obtain
y ^ b = S b P θ ^ = S b p 1 θ ^ 1 + S b P 2 θ ^ 2 S b p 1 ( u 1 u 1 ) 1 u 1 y a = y ¯ a ι n m , ( λ ) .
The final equality in (A6) follows from u 1 = S a p 1 = S a ( 1 n ι n ) = 1 n ι m and S b p 1 = S b ( 1 n ι n ) = 1 n ι n m .   □

References

  1. Yamada, H. Geary’s c and spectral graph theory: A complement. Mathematics 2023, 11, 4228. [Google Scholar] [CrossRef] [Scilit]
  2. Geary, R.C. The contiguity ratio and statistical mapping. Inc. Stat. 1954, 5, 115–145. [Google Scholar] [CrossRef] [Scilit]
  3. Cliff, A.D.; Ord, J.K. The problem of spatial autocorrelation. In Studies in Regional Science; Scott, A.J., Ed.; Pion: London, UK, 1969; pp. 25–55. [Google Scholar]
  4. Cliff, A.D.; Ord, J.K. Spatial autocorrelation: A review of existing and new measures with applications. Econ. Geogr. 1970, 46, 269–292. [Google Scholar] [CrossRef] [Scilit]
  5. Cliff, A.D.; Ord, J.K. Spatial Autocorrelation; Pion: London, UK, 1973. [Google Scholar]
  6. Cliff, A.D.; Ord, J.K. Spatial Processes: Models and Applications; Pion: London, UK, 1981. [Google Scholar]
  7. Von Neumann, J. Distribution of the ratio of the mean square successive difference to the variance. Ann. Math. Stat. 1941, 12, 367–395. [Google Scholar] [CrossRef] [Scilit]
  8. Hodrick, R.J.; Prescott, E.C. Postwar U.S. business cycles: An empirical investigation. J. Money Credit Bank. 1997, 29, 1–16. [Google Scholar] [CrossRef] [Scilit]
  9. Yamada, H. Trend extraction from economic time series with missing observations by generalized Hodrick–Prescott filters. Econom. Theory 2022, 38, 419–453. [Google Scholar] [CrossRef] [Scilit]
  10. Bapat, R.B. Graphs and Matrices, 2nd ed.; Springer: London, UK, 2014. [Google Scholar]
  11. Estrada, E.; Knight, P. A First Course in Network Theory; Oxford University Press: Oxford, UK, 2015. [Google Scholar]
  12. Gallier, J. Spectral theory of unsigned and signed graphs. Applications to graph clustering: A survey. arXiv 2016, arXiv:1601.04692. [Google Scholar] [CrossRef] [Scilit]
  13. Yamada, H. Geary’s c and spectral graph theory. Mathematics 2021, 9, 2465. [Google Scholar] [CrossRef] [Scilit]
  14. Beck, A. Introduction to Nonlinear Optimization Theory, Algorithms, and Applications with MATLAB; Society for Industrial and Applied Mathematics: Philadelphia, PA, USA, 2014. [Google Scholar]
  15. Yamada, H. Spatial smoothing using graph Laplacian penalized filter. Spat. Stat. 2024, 60, 100799. [Google Scholar] [CrossRef] [Scilit]
  16. Hoerl, A.E.; Kennard, R.W. Ridge regression: Biased estimation for nonorthogonal problems. Technometrics 1970, 12, 55–67. [Google Scholar] [CrossRef]
  17. Roberts, D.R.; Bahn, V.; Ciuti, S.; Boyce, M.S.; Elith, J.; Guillera-Arroita, G.; Hauenstein, S.; Lahoz-Monfort, J.J.; Schröder, B.; Thuiller, W.; et al. Cross-validation strategies for data with temporal, spatial, hierarchical, or phylogenetic structure. Ecography 2017, 40, 913–929. [Google Scholar] [CrossRef] [Scilit]
  18. MacQueen, J. Some methods for classification and analysis of multivariate observations. In Proceedings of the Fifth Berkeley Symposium on Mathematical Statistics and Probability, Volume 1: Statistics; University of California Press: Berkeley, CA, USA, 1967; pp. 281–297. [Google Scholar]
Figure 1. A connected undirected graph. Values at colored vertices are missing.
Mathematics 14 01435 g001
Figure 2. Root mean squared error (RMSE) as a function of the smoothing parameter λ , evaluated via spatial block cross-validation. The optimal value of λ , indicated by a red dashed line, is 0.1874 .
Mathematics 14 01435 g002
Figure 3. Observed data with 30% of values randomly removed (top left), imputed data using the proposed graph-based interpolation method (top right), and the original complete data (bottom left).
Mathematics 14 01435 g003
Figure 4. Graph Laplacian eigenvectors p i for i = 2 , 3 , 4 , 100 , 120 , 140 . In each panel, the first element of the ordered pair denotes the index i, and the second gives the value of p i L p i .
Mathematics 14 01435 g004
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.