1. Introduction
Urban areas are dominant contributors to global energy consumption, accounting for over 60% of the total final energy use worldwide [
1]. Driven by accelerating urbanization and sustained population growth, the demand for building energy is projected to increase [
2]. It has been shown that the worldwide energy use may increase in 2050 by almost 90% with respect to the 2003 values [
3]. Also, it has been predicted that the primary energy may rise by 70% from 2013 to 2050 [
4]. Since most of the growing need is given by nonrenewable energy, this has led to some very important ecological consequences, such as global warming [
5] and air pollution [
6,
7,
8]. The international agreement has been already reached in need of a reduction of both the energy use and the carbon emission. In this context, precise urban building energy modeling (UBEM) [
9,
10] has become essential for evaluating energy efficiency potentials of buildings; developing urban design strategies; and supporting the shift to sustainable, low-carbon urban environments.
With the increase in academic research on urban energy consumption, techniques like building energy modeling (BEM) [
11,
12] and building performance simulation (BPS) [
3,
13] are widely used. The move from BEM to urban building energy modeling (UBEM) is a move from the analysis of a single building to the analysis of a complex urban environment [
14]. The UBEM is an important planning tool for architects, city designers, and governments that make energy policies [
15]. Traditionally, UBEM methods are divided into “top-down” and “bottom-up” approaches.
Top-down approaches treat the building volumes as a uniform unit, linking factors such as macroeconomic indicators [
16] and climate conditions [
17] to calculate energy consumption [
18,
19]. These models need limited data input; however, they do not account for the architecture details and the spatial relations (i.e., inter-building effects) of the compact urban building layout [
20].
In contrast, bottom-up methods analyze energy consumption based on detailed end-use data, which are further classified into physics-based and data-driven models [
21]. Physics-based models rely on thermodynamic laws and BPS [
22], such as EnergyPlus [
12] (platforms such as CityBES [
23] or UMI [
24]). Although capable of high-fidelity simulations, they demand extensive computational resources and input data, which are often unavailable at a city scale, leading to a reliance on default assumptions that compromise accuracy [
3,
5,
25]. Data-driven models have emerged as a prominent alternative [
26,
27,
28], using machine learning algorithms (e.g., support vector machines (SVMs) [
29] and gradient boosting algorithms (XGBoost) [
30]) and deep learning architectures (e.g., Recurrent Neural Network [
31] and Artificial Neural Network [
32]). However, the complex spatial characteristics of an urban layout and the impact of inter-building effect (IBE) often result in significant errors in the predictions of data-driven models. Additionally, since many data-driven models are black boxes [
33,
34], their interpretability is limited, which prevents their more general use in urban planning and policy making [
5].
Graphs, as data structures that represent connected elements, provide an excellent way to describe urban layouts [
35,
36]. Graph structures are similar to network structures in that they can both describe the signal transmission and aggregation between nodes [
37]. However, their irregular topology gives challenges for conventional neural networks (CNNs), which fail to capture the relationships from the dataset since CNNs require data arranged in grids or sequences [
38]. To address this limitation, graph neural networks (GNNs) have emerged as a promising alternative by aggregating information from neighboring nodes. In the context of urban block design, GNN-based surrogate models offer the following advantages: they simultaneously account for individual building morphology and surrounding environment, exhibiting superior generalizability for different types of urban morphology [
39]. The existing literature created a Shadow Attention Graph Neural Network (SAGNN) to advance solar radiation forecasting for urban edifices, thereby facilitating the realization of Net-Zero Energy Buildings (NZEBs) in New York City [
40]. Concurrently, multi-building load prediction has been framed as a spatial contextual learning paradigm, wherein inter-building interactions are explicitly formalized by graph representations utilizing three years of hourly power consumption data across 24 facilities, integrated with coupled meteorological variables and EnergyPlus-simulated solar profiles [
41]. These advancements emphasize the efficacy of GNNs in simulating building physics under urban microclimates, verifying that graphs can capture shading effects among adjacent buildings. Recent studies have constructed heterogeneous graphs encapsulated multidimensional urban entities―including buildings, streets, intersections, and plots [
42]. Through relation-aware message passing and feature fusion, such frameworks successfully map intricate urban environments into structured topological data to predict localized building attributes.
Despite these advancements, current GNN-based UBEM research still has many important problems:
Context limitation: BEM-focused GNN studies often use homogeneous graphs for internal zones and overlook external environmental influences from surrounding buildings [
43].
Morphological simplification: Existing UBEM studies often simplify buildings into single nodes, thereby failing to account for the impact of detailed building shape on energy performance [
44].
Algorithm limitation: Most studies only used one or two GNN algorithms, ignoring the significant differences in aggregation strategies among different GNN architectures and thereby limiting the robustness of the findings [
45].
Interpretability issues: There is an absence of post hoc interpretability analysis, which means that the underlying “decision-making” processes of these surrogate models remain unverified [
46].
To address these gaps, this study introduces a novel, interpretable, data-driven UBEM framework designed to integrate IBE for accurate and widely applied urban building energy prediction. The block-level relationship graph (BRG) is a special heterogeneous graph [
47] dataset which is constructed in a systematic way to record the building forms and urban spatial layout by parametric modeling methods. By evaluating and comparing four GNN architectures (Graph Convolutional Network (GCN), Graph Sample and Aggregation (GraphSAGE), Graph Attention Network (GAT), and GraphTransformer), this study identified the optimal model for urban building energy prediction. Finally, the GNNExplainer algorithm was used to perform an interpretability analysis, quantifying feature importance and visualizing signal-propagation patterns to verify the physical rationality of the predictive mechanism of the final model.
The objectives of this research are as follows:
2. Methodology
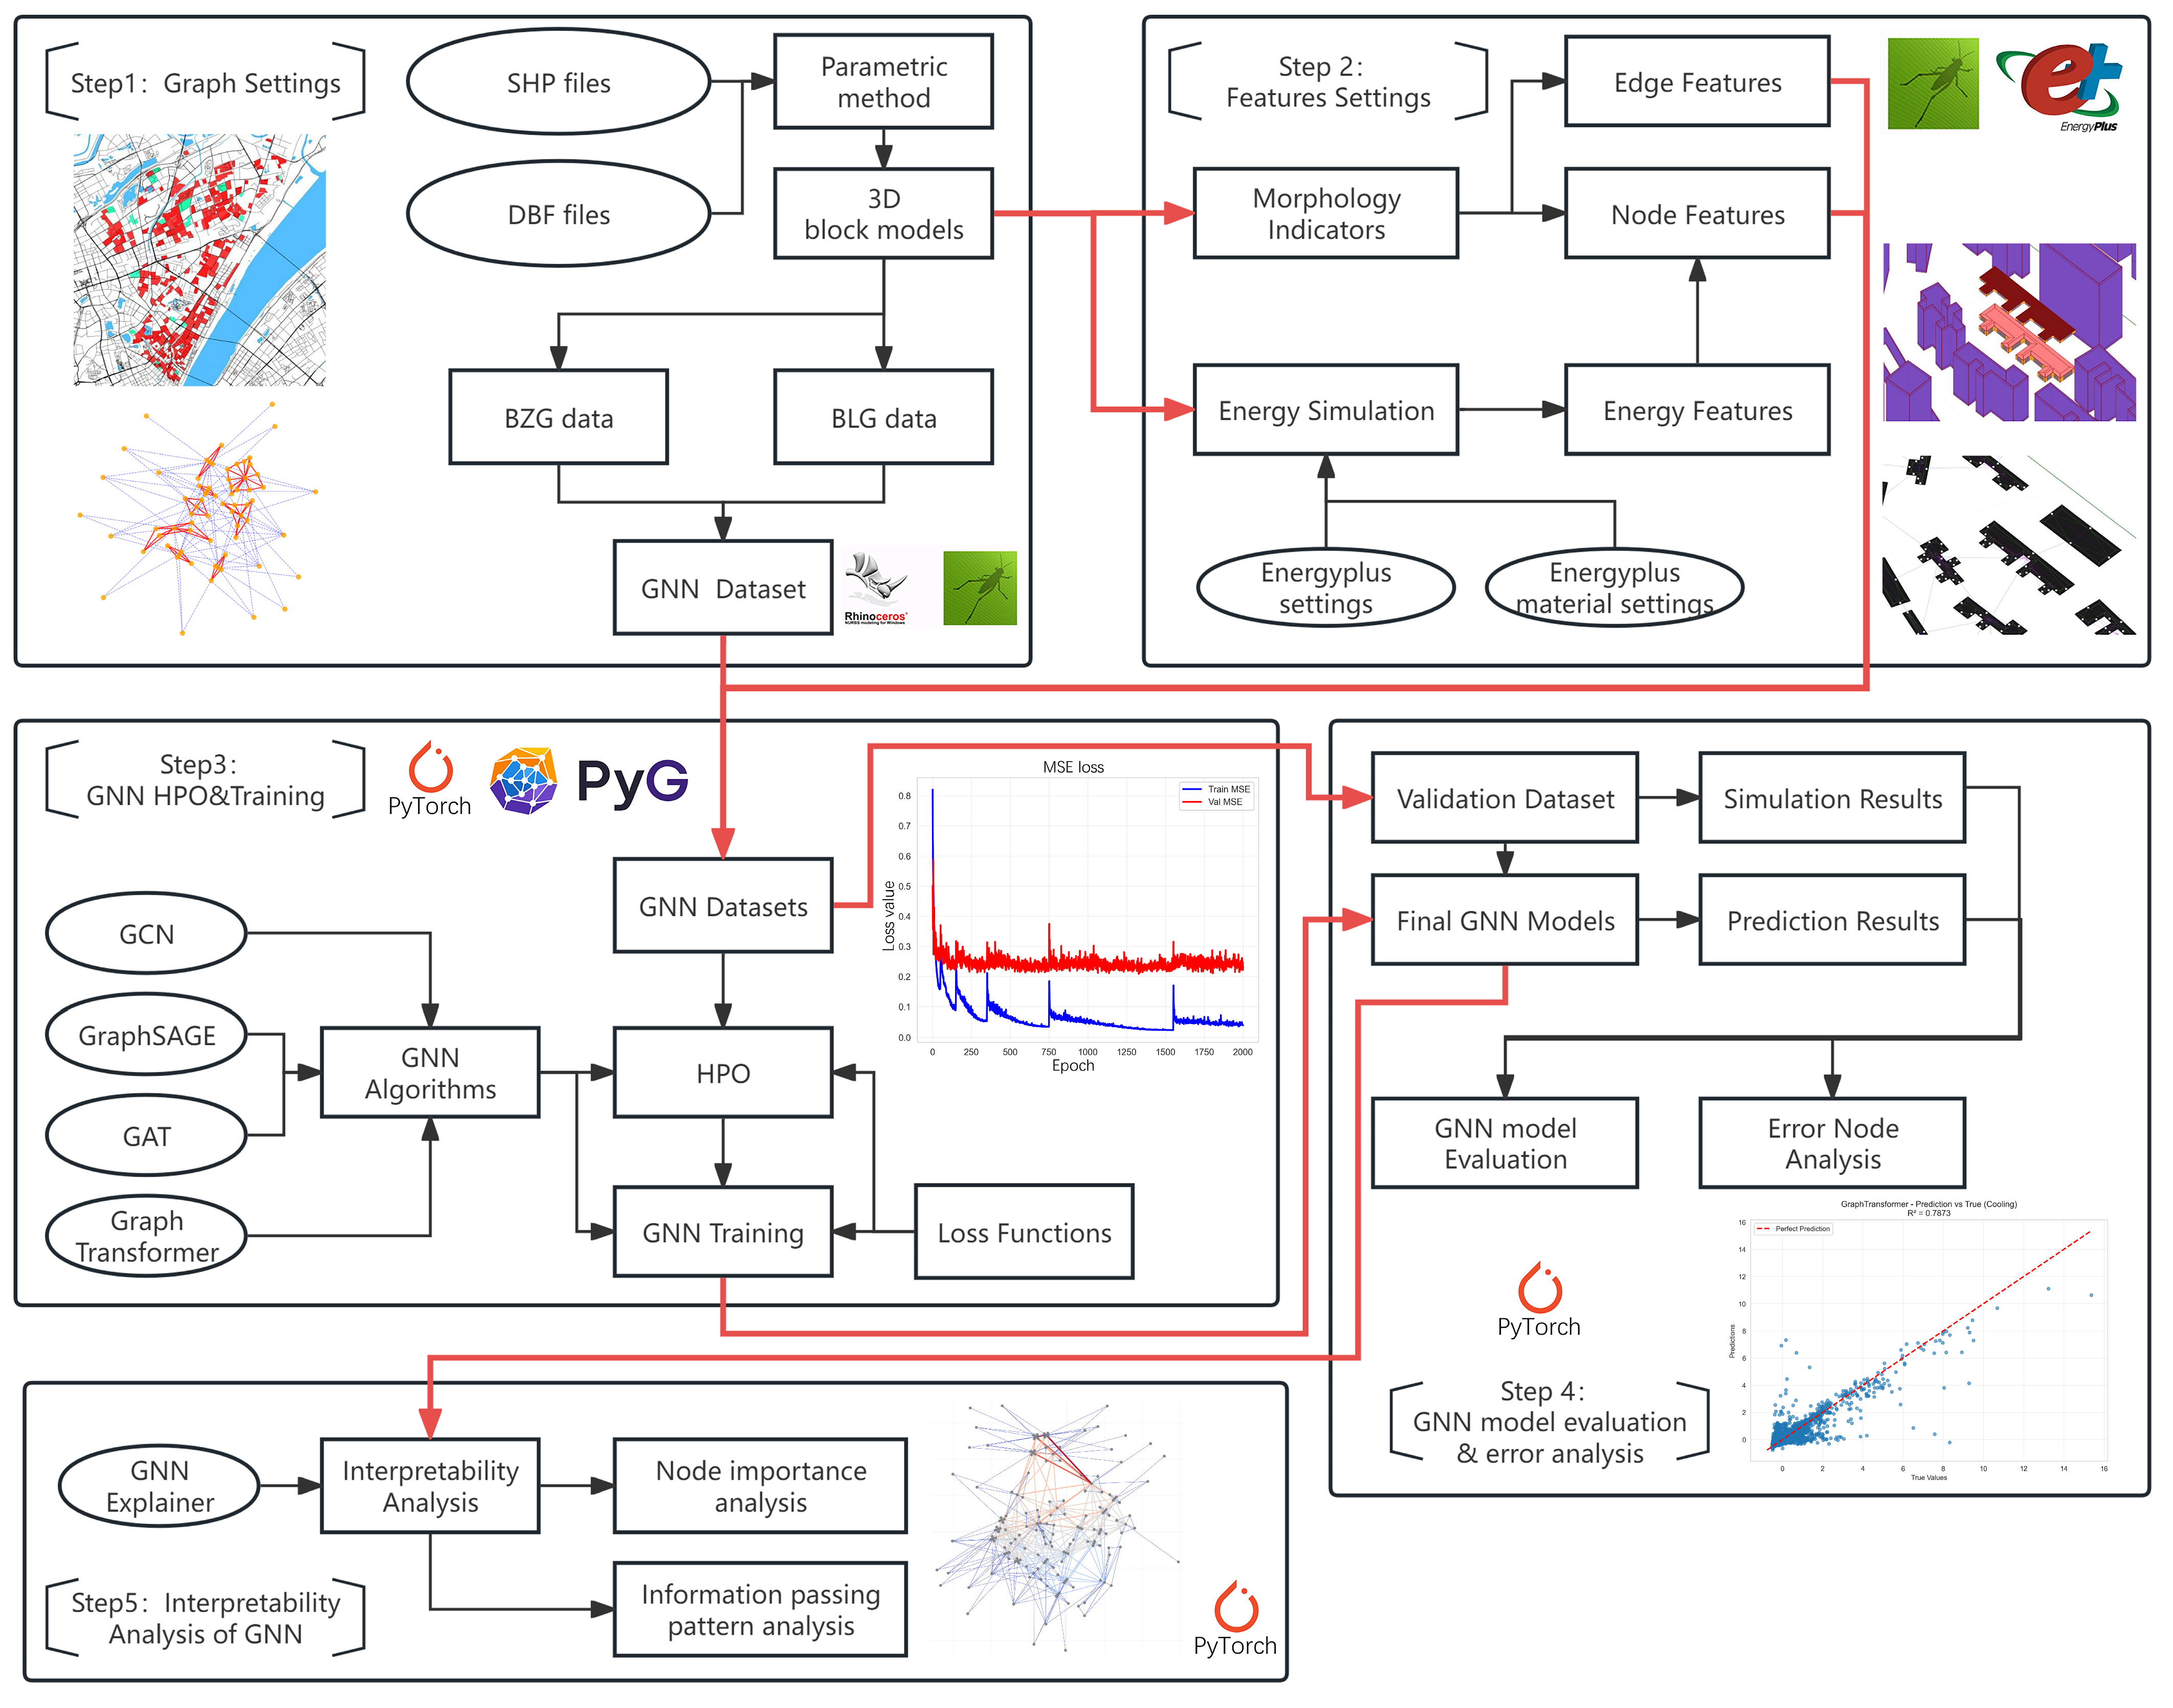
As shown in
Figure 1, this section shows the research framework, which integrates graph data generation, building energy simulation (BES), GNN model training and validating settings, and GNNExplainer settings:
Phase I (graph construction): Based on urban block building information, this study generates heterogeneous graph data by parametric methods (
Section 2.1). The graph architecture comprises two connection types: (1) the Building Zone Graph (BZG) and (2) the Building Layout Graph (BLG).
Phase II (feature engineering): Morphological indicators are used to define node and edge features in each graph. Concurrently, node-level energy consumption features are generated by the BPS method (
Section 2.2).
Phase III (algorithm architecture): Four GNN algorithms are introduced in
Section 2.3. This phase also introduces the heterogeneous graph encoding strategies specific to each GNN algorithm.
Phase IV (model training and optimization): The baseline and the search space of hyperparameter settings in four GNN algorithms are introduced. Subsequently, the models are trained and evaluated using a multi-objective loss function strategy (
Section 2.4).
Phase V (interpretability analysis): Post hoc interpretability of the GNN models is conducted using the GNNExplainer algorithm to identify key features and verify physical rationality (
Section 2.5).
2.1. Graph Construction
The urban system exhibits a complex hierarchical structure, which stems from the interaction, feedback effect, and scaling process of urban form and function across multiple levels [
53]. This study uses a heterogeneous graph method to effectively represent the detailed morphological features of individual buildings and their complex spatial relationships in urban blocks. Unlike traditional homogeneous graphs [
54,
55] that consist of only one type of node and edge, heterogeneous graphs include multilevel types of nodes and edges. By maintaining semantic information, the heterogeneous graph enables the investigation of deep connections between different types of nodes using techniques such as meta-paths.
This study proposes a dual-level graph framework, which hierarchically integrates the Building Zone Graph (BZG) and the Building Layout Graph (BLG). This hierarchical strategy enables a detailed representation of the morphological and topological features critical to energy performance analysis.
The dataset, comprising these heterogeneous graph sub-datasets, was divided as follows:
Model training and testing (90%): This sub-dataset is used for training and validation, further subdivided into training (70%) and testing (30%) sets to support the iterative optimization of the four GNN algorithms.
Final verification (10%): This part of the separate dataset is used as an independent validation set to verify predictive accuracy and generalizability of the final model when used for a different type of urban layout.
2.1.1. Heterogeneous Graph
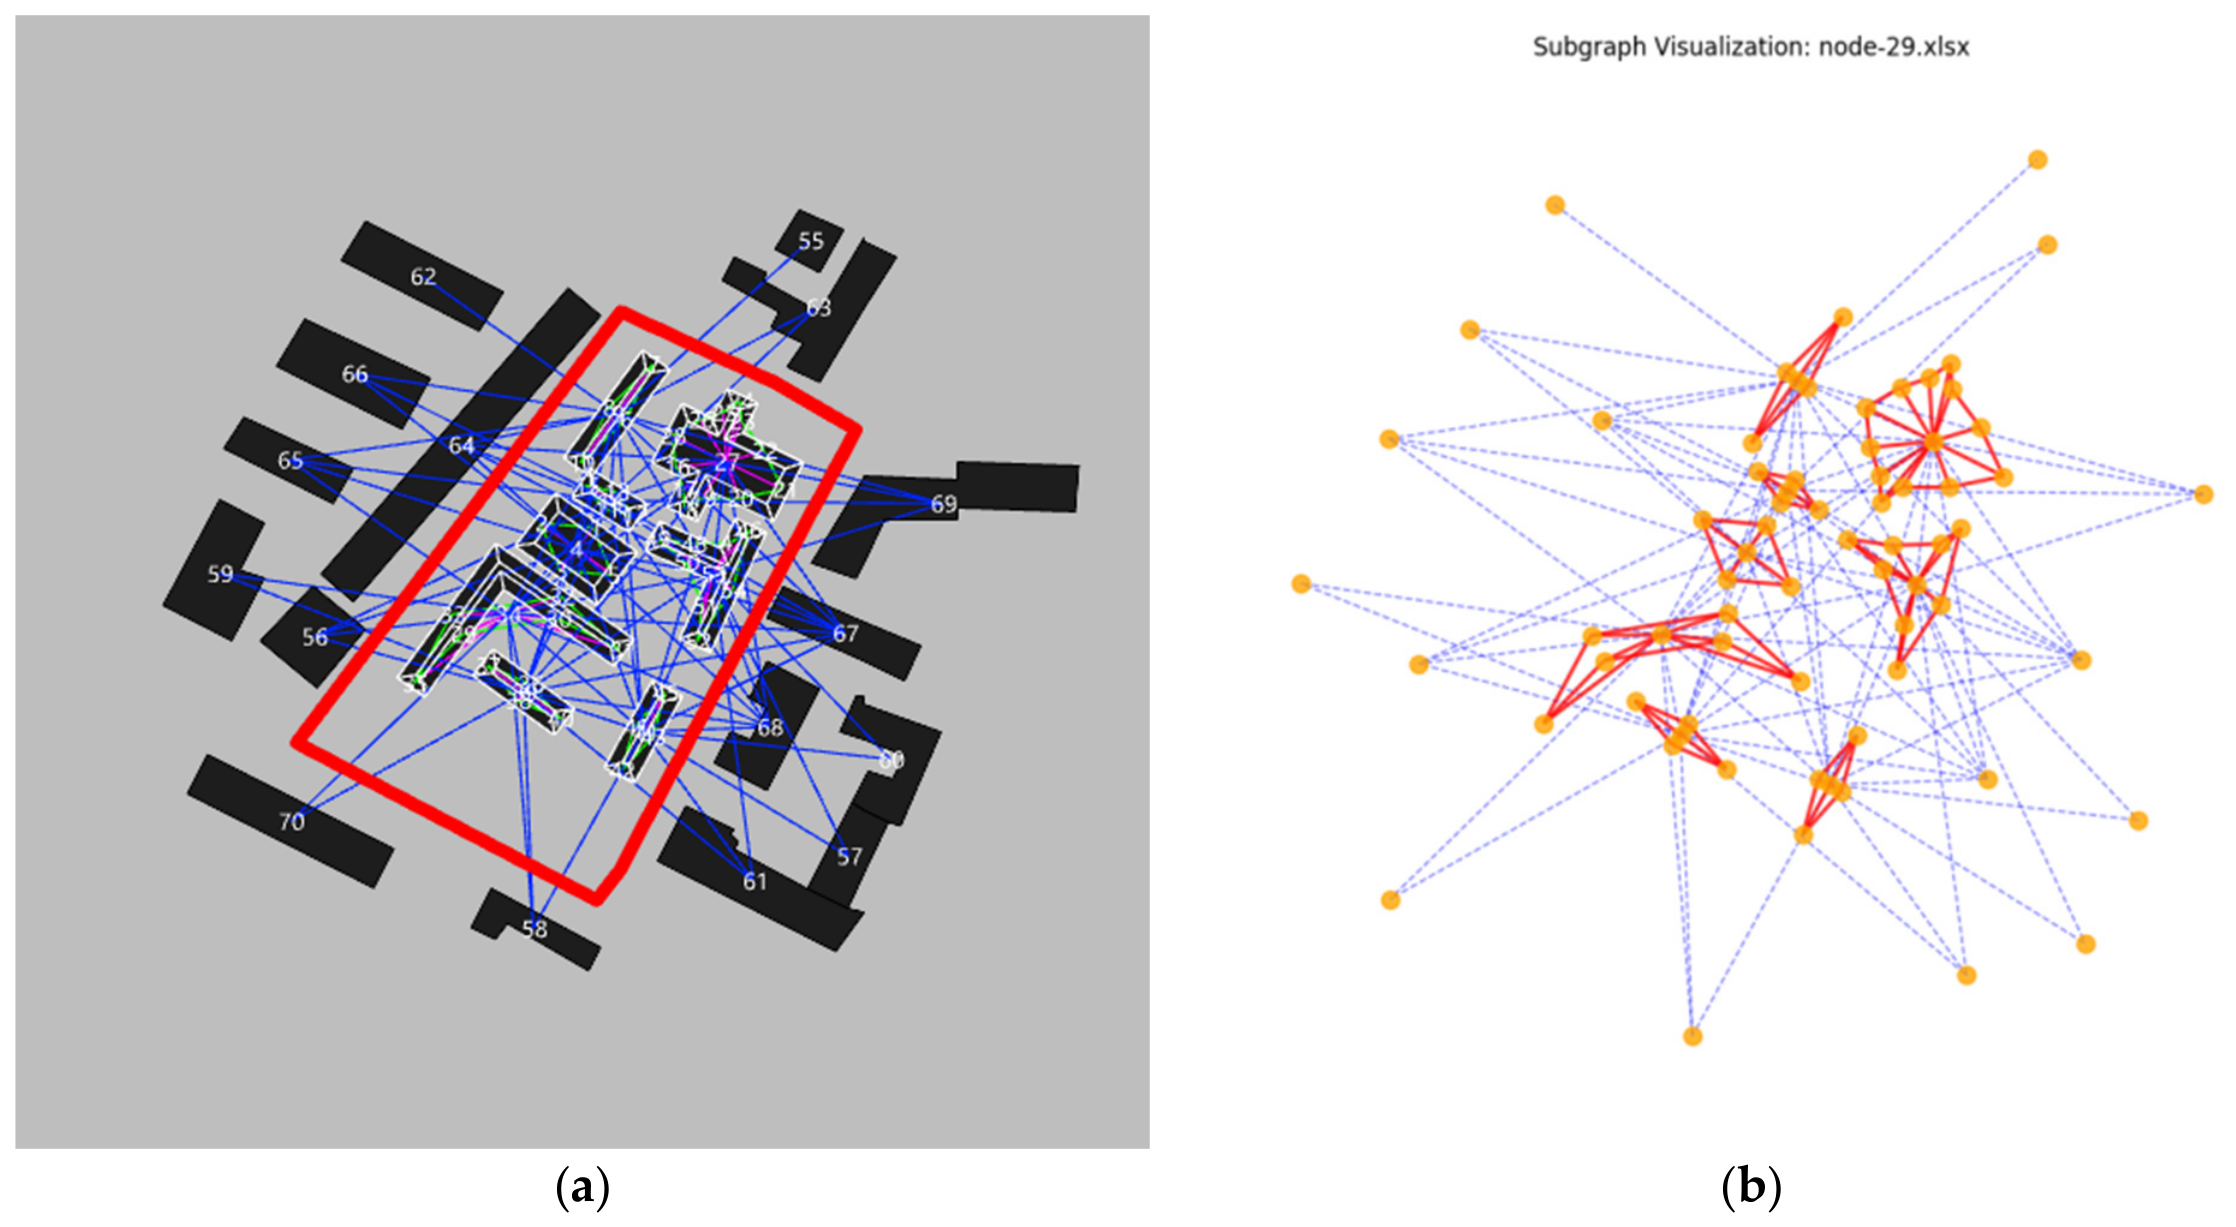
As illustrated in
Figure 2a, the heterogeneous graph for each block is generated from the building layout by parametric modeling through a two-step process:
Building Zone Graph (BZG): Each building in the block is subdivided into functional zones. The topological connectivity between these zones is established to construct the BZG, which captures the internal spatial relationships of the building.
Building Layout Graph (BLG): The centroids of buildings―both in the target block and in the surrounding context―are extracted. Connections are then established between these centroids to form the BLG, which represents the urban layout.
As shown in
Figure 2b, the heterogeneous network integrates these two types of sub-graph: BZG edges (red) represent inter-zone connectivity, whereas BLG edges (blue) represent inter-building spatial relationships.
2.1.2. BZG Configuration
As shown in
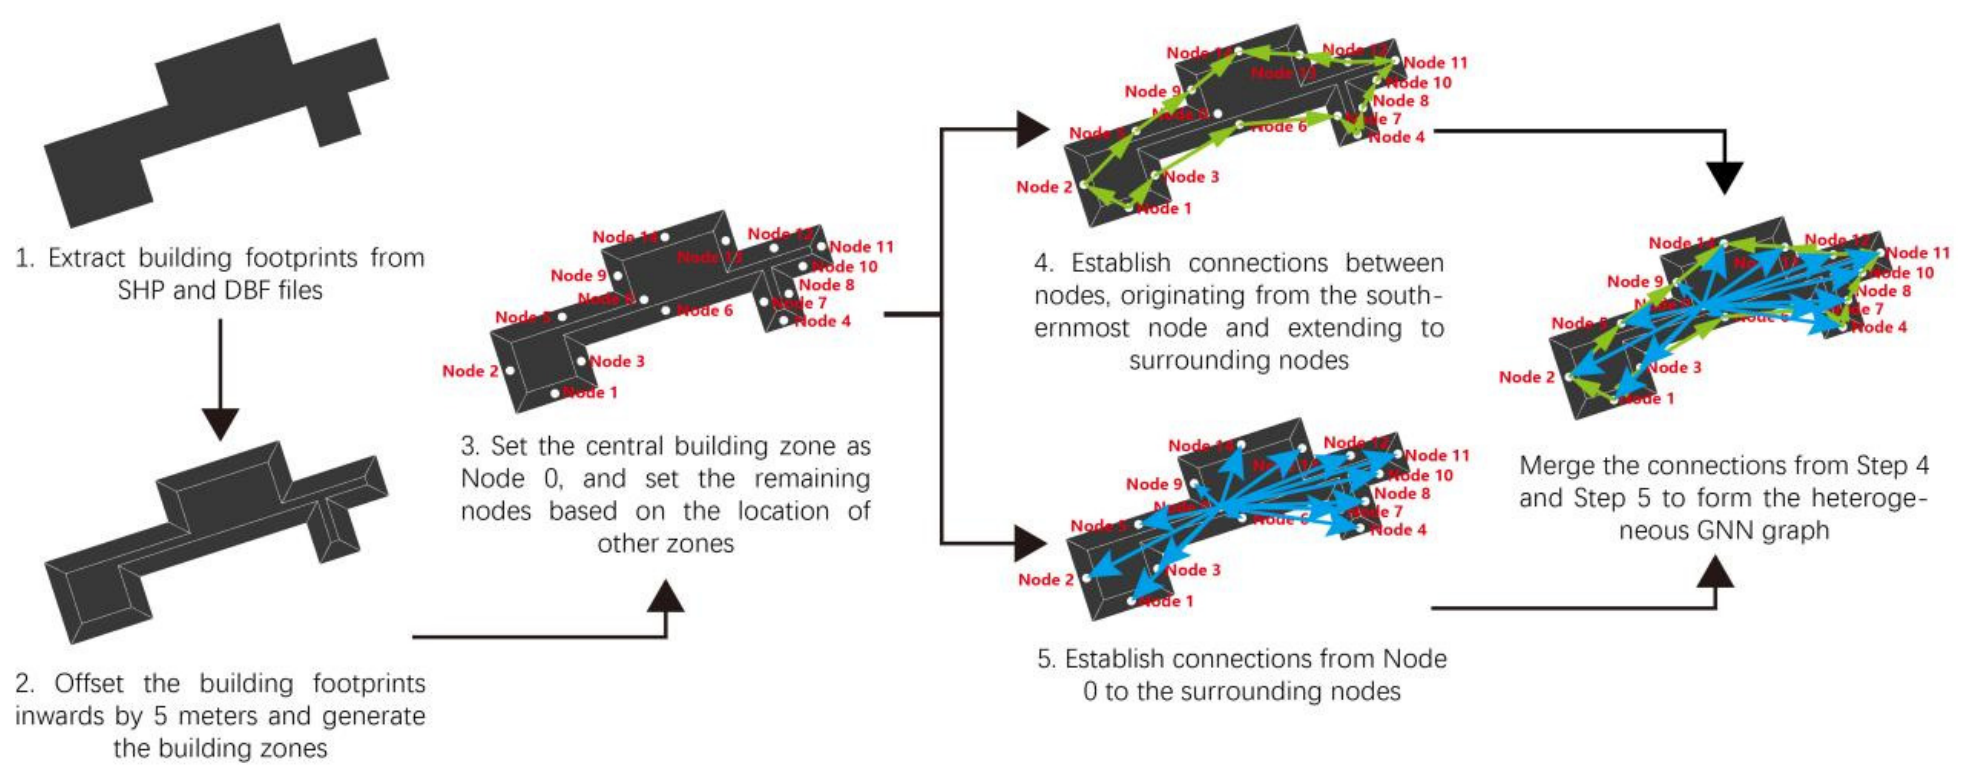
Figure 3, the generation process for the Building Zone Graph (BZG) is defined by the following two steps:
Node definition: Each building footprint was processed with a 5 m internal offset to create a central core zone (
), representing the interior thermal space [
43]. The remaining peripheral area was subsequently divided into
directional zones (
to
) based on their spatial orientation.
Edge definition:
- (1)
Core-to-peripheral connectivity: Directed edges are established from the centroid of the core node () to each centroid of the nodes ( to ).
- (2)
Peripheral-to-peripheral connectivity: Directed edges are established between the adjacent peripheral zones. To maintain directional consistency and minimize topological redundancy, these edges originate from the centroid of the south-facing zone and extend sequentially to its neighboring zones.
2.1.3. BLG Configuration
As shown in
Figure 2a,b, to address the significant variability in building layouts of the residential blocks in Wuhan, a standardized and simplified graph model is created by a three-step process:
Node definition: Each building in the target block is represented by a node set at the centroid of its core zone (). Because neighboring buildings outside the block may influence the microclimate in the target block, surrounding buildings within a 200-meter radius around the block are included in the graph. These surrounding buildings are represented by single nodes at their geometric centers.
Edge generation: Connections between nodes are established based on layout. Initially, all possible pairwise links between buildings inside the block and the neighboring external buildings are generated.
Edge filtering: To optimize GNN efficiency, edge filtering thresholds were determined based on the physical and solar boundary conditions of Wuhan. (1)
(200 m): the residential buildings in Wuhan are generally under 100 m (33 stories). The 200 m threshold represents twice the maximum building height, ensuring all critical mutual shading is captured. (2)
(
to
): Wuhan is located at
latitude. Based on solar azimuth trajectories in the Northern Hemisphere, context buildings located in the due-north sector of a target building (
to
) will never cast solar shadows onto the target building. The
and
are detailed in
Table 1.
2.2. Feature Engineering
This study used parametric methods to extract a set of features for both nodes and edges. For node features, morphological indicators of the corresponding building zones are generated to serve as node morphology features. Simultaneously, building energy consumption for each zone in the block is simulated with EnergyPlus, and the simulation results are integrated as node energy features. Additionally, edge features are also generated using the same parametric framework to complete the dataset for the GNN models.
2.2.1. Node Morphology Features
Previous studies have shown that differences in building geometry significantly influence energy consumption. To capture the impact of these geometric characteristics, specific morphological indicators are incorporated into the GNN model as node features. Based on the previous research [
23,
56,
57], this study identifies key indicators affecting building energy performance. Furthermore, although the graph topology captures the building layouts and relative connectivity, it does not explicitly represent the exact spatial coordinates of each zone. To address this limitation, two additional indicators are introduced to define the precise spatial relationship between each node and the center of the block. Using the block center as the origin, the east–west distance (
) and north–south distance (
) were calculated for each node.
and
were integrated into the GNN model as supplementary morphological features, as detailed in
Table 2.
2.2.2. Node Energy Features
This study uses Energy Use Intensity (EUI) [
58] as the main indicator for evaluating building energy performance. Since Wuhan is a typical hot-summer and cold-winter city, both the summer-cooling and winter-heating energy load of buildings are critical considerations [
59]. Accordingly, EUI is defined as the annual building average heating (
) and cooling (
) system loads for all vertical spaces within each building zone, providing a comprehensive representation of the annual energy demand. The node energy features are summarized in
Table 3.
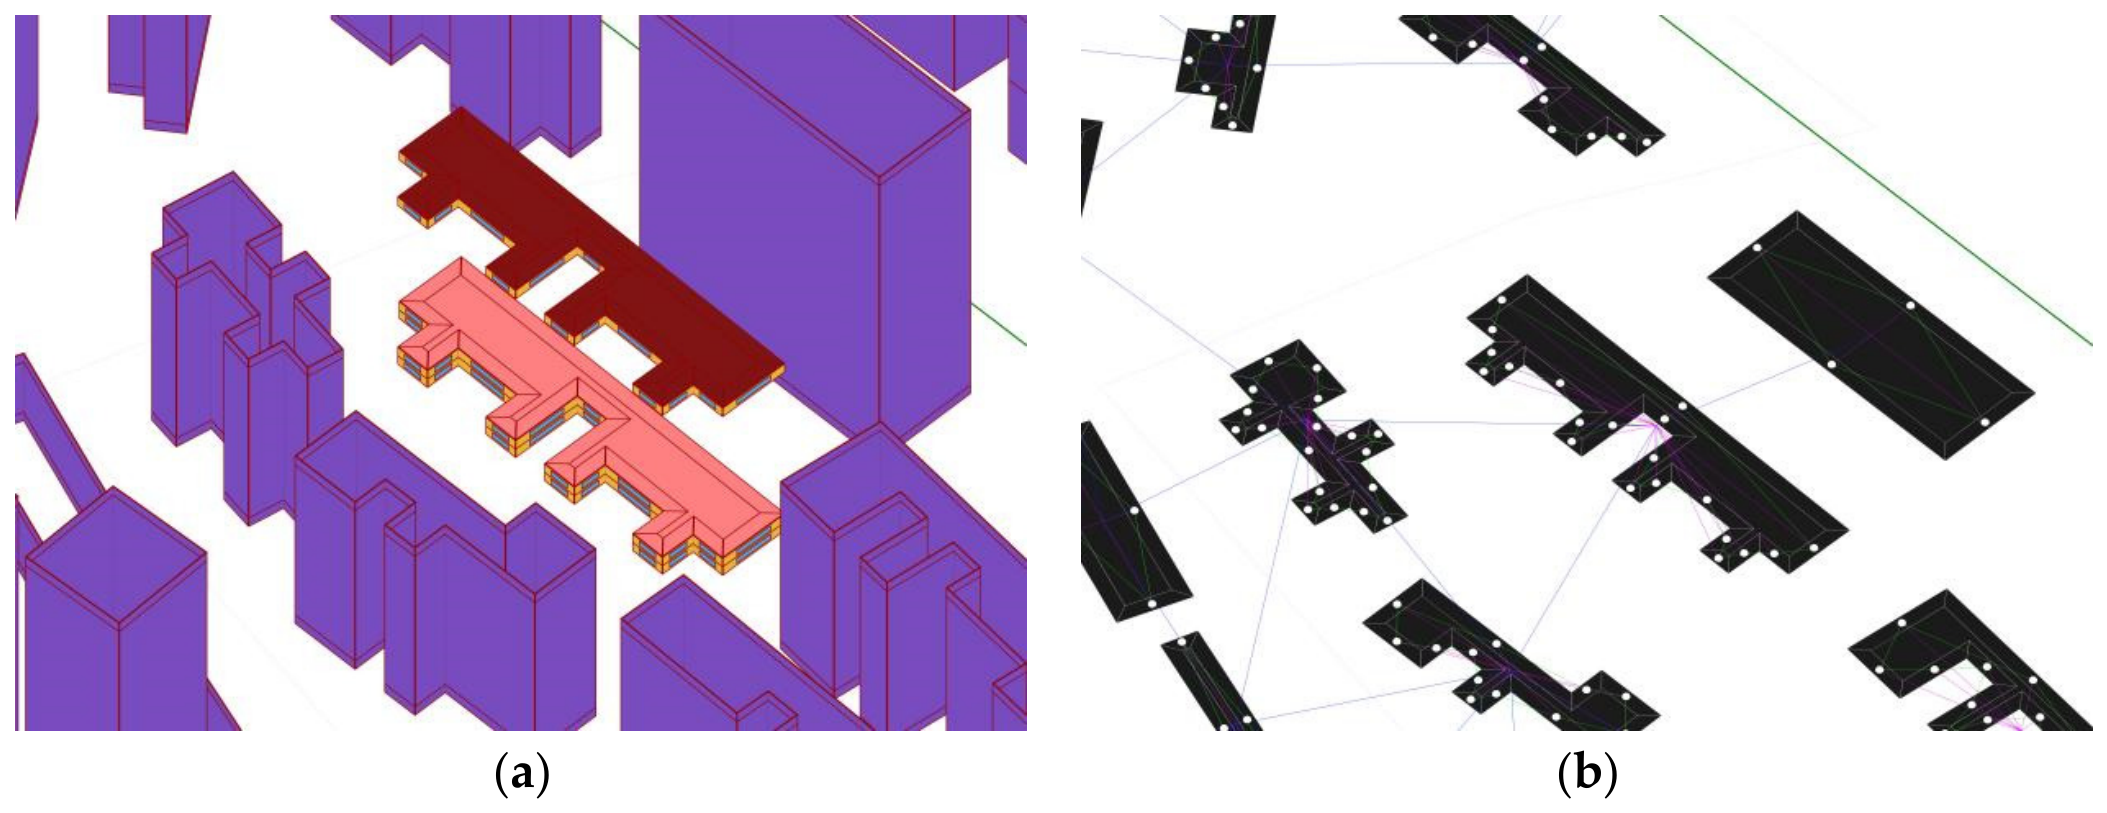
To reduce the high computational costs associated with large-scale, block-level energy simulations, a three-layer simulation strategy [
60]―comprising bottom, middle, and top building floors―is used, as shown in
Figure 4a. In
Figure 4b, each node in the graph represents the aggregated energy consumption of all vertical building units within its corresponding zone. This abstraction enables efficient modeling while maintaining high simulation accuracy.
The building annual heating (
) and cooling (
) loads were simulated by EnergyPlus [
61] with Typical Meteorological Year (TMY) data [
62]. The simulations were performed within the Grasshopper parametric platform, using the Honeybee [
63,
64] and Dragonfly [
58,
65] plugins. To align with the template-based workflow of Dragonfly, the initial configurations were based on the ASHRAE 90.1-2015 standard [
66].
Furthermore, to reflect local conditions in Wuhan, the simulation parameters were adjusted to follow with regional design codes. Consequently, key parameters, including building envelope materials, internal heat gains, lighting power densities, occupant densities, HVAC set points, and operational schedules, were set according to both national (GB50189-2015) and regional (DB42/301-2023) standards. These simulated results were then normalized and integrated with the previously established graph structures and node features to create the database for training and validating the GNN models. The detailed simulation settings and material properties are summarized in
Table 4,
Table 5 and
Table 6.
2.2.3. Edge Features
Although heterogeneous graphs effectively capture the relationships between building nodes both within and surrounding the block, these edges typically represent topological connections. To ensure the model accounts for real-world geometric information, it is essential to specify physical attributes such as distance and orientation. This study defines edges using two features: edge angle (
) and edge distance (
). The edge features are summarized in
Table 7.
Because some GNN architectures, such as GCN and GraphSAGE, are not designed to process multidimensional edge features directly, a mapping transformation method is used. This method converts the multidimensional edge attributes into optimized scalar weights to ensure compatibility with the message-passing mechanisms of all GNN models.
2.3. GNN Algorithms
Different GNN algorithms use different information aggregation mechanisms, leading to variations in how they handle multilevel edge relationships and features. These methodological differences often result in performance differences when models are trained on complex heterogeneous graphs. To comprehensively evaluate the performance of GNNs on the two-hop heterogeneous graphs, this study uses four GNN architectures with different aggregation approaches, as summarized in
Table 8. These four GNN algorithms exhibit algorithmic divergence in their information aggregation paradigms and network. To systematically evaluate the efficacy of attention mechanisms, performance benchmarks were established comparing two non-attentional frameworks (GCN and GraphSAGE) against two attention-driven GNN algorithms (GAT and GraphTransformer). Furthermore, a comparative analysis between GAT and GraphTransformer was used to discern the operational effectiveness and representational capacities of localized versus global attention mechanisms within the building energy prediction.
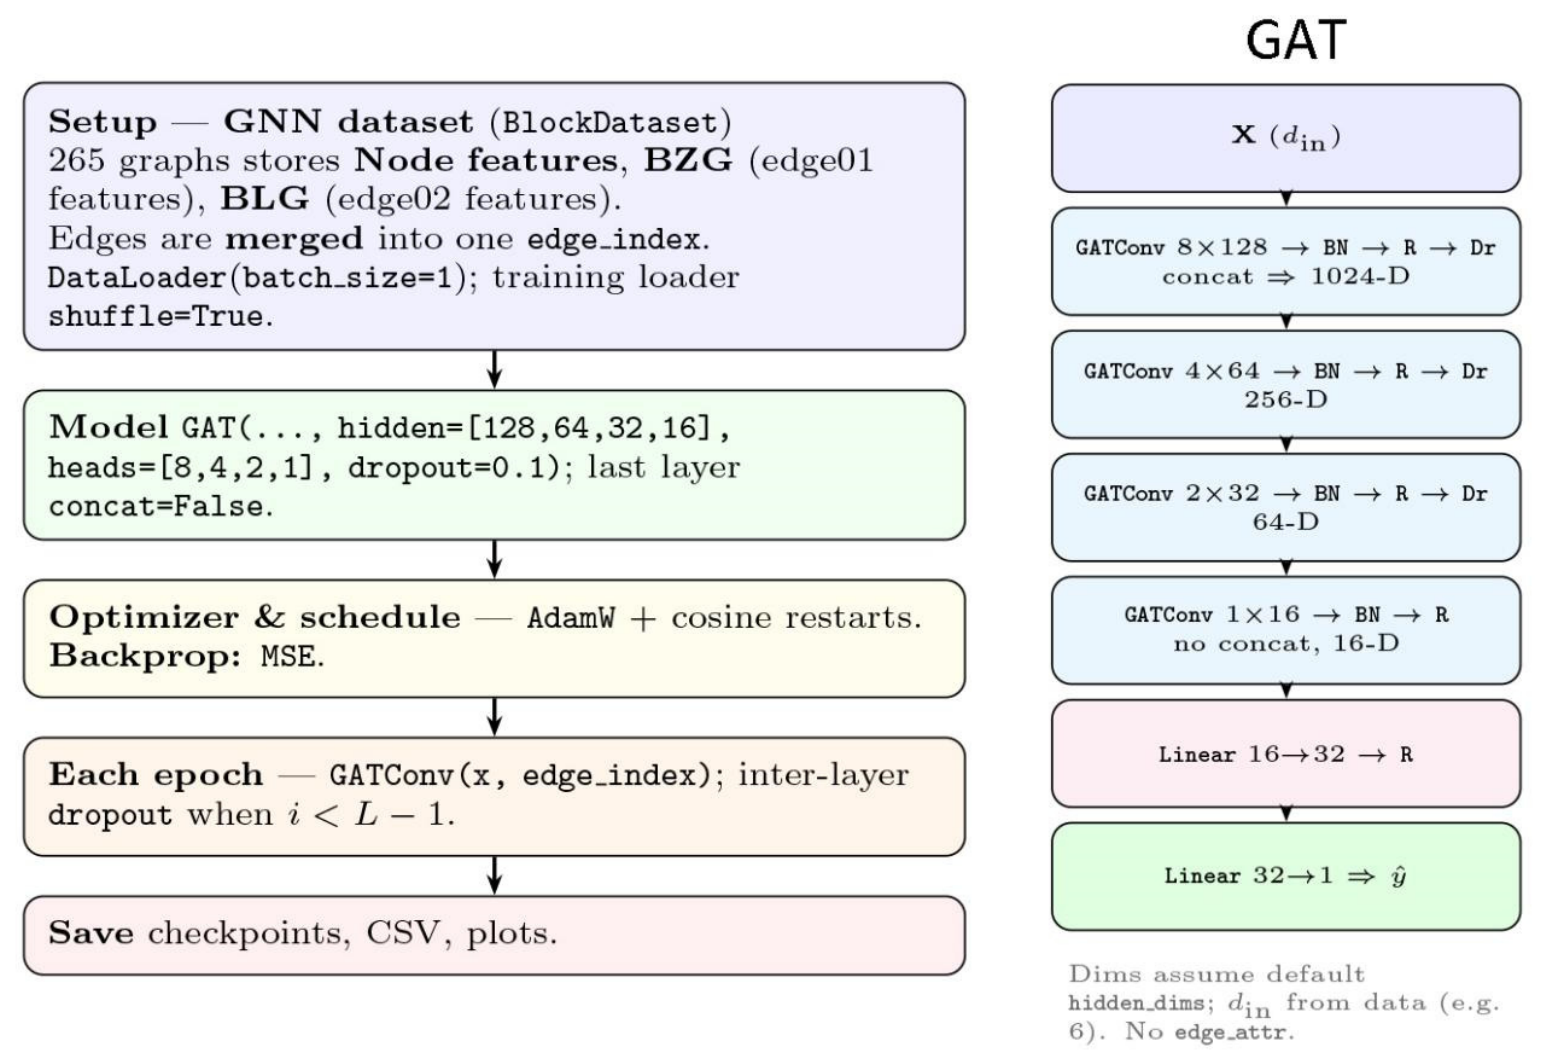
To ensure a rigorous and consistent comparison, all relationship types are classified into one-hop edges (edge 1: BZG) and two-hop edges (edge 2: BLG). In the encoding phase, all four models use a unified framework characterized by relation-specific message passing, fusion through cross-relation summation, and nonlinear transformations between layers. This standardized pipeline ensures fairness between all models.
The main difference between the GNN models is how they handle message passing and incorporate features:
GCN and GraphSAGE: These models convert edge features into scalar weights before performing weighted propagation. This approach aligns with spectral-domain normalized aggregation for GCN, and neighborhood means aggregation for GraphSAGE.
GAT and GraphTransformer: These architectures directly integrate edge features into attention-based calculations. They utilize multi-head mechanisms to learn the relative contributions of different neighboring edges, including two-hop connections, to the target node.
2.3.1. Graph Convolutional Network (GCN)
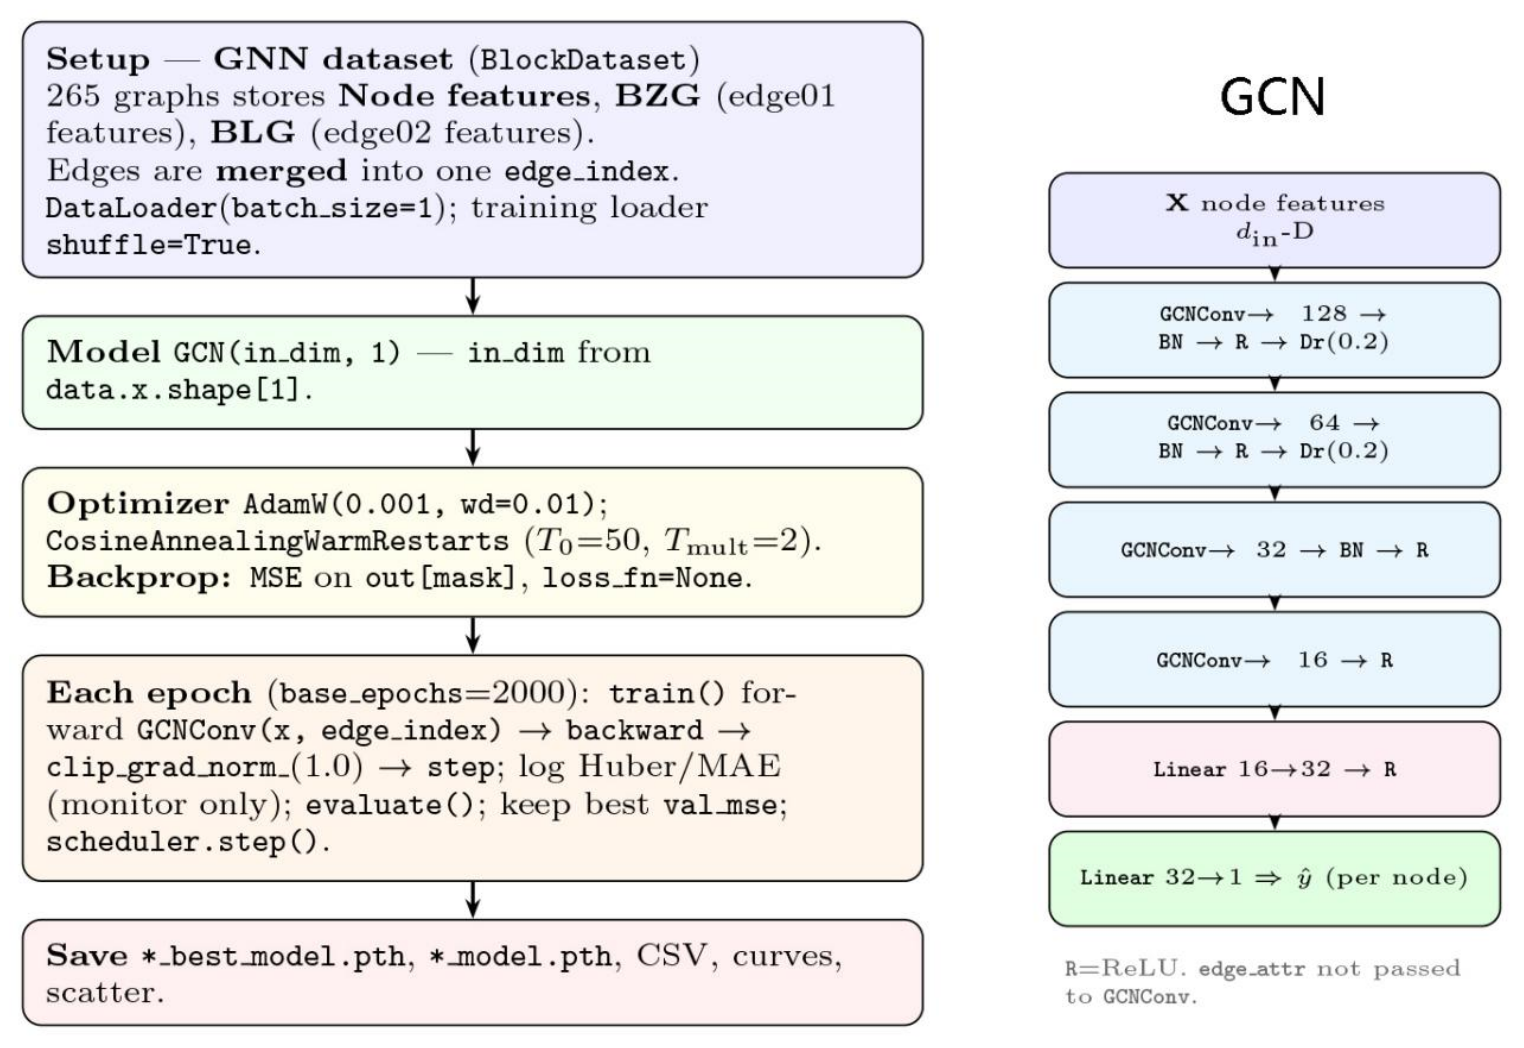
GCN is a spectral-based GNN that is designed for graph-structured data. Its core mechanism relies on message passing and neighborhood aggregation, in which nodes are updated through a weighted combination of features from adjacent nodes. The layer-wise propagation rule is defined as follows:
where
is the adjacency matrix with added self-loops,
is the corresponding diagonal degree matrix,
represents the node feature matrix at layer
,
is a learnable weight matrix, and
denotes the nonlinear activation function.
GCN supports transductive learning, enabling effective representation learning for graph structures. Furthermore, by sharing parameters among nodes, they greatly decrease the complexity of the model and the computational cost. However, the GCN architecture is susceptible to over-smoothing, in which multiple rounds of aggregation cause node embedding to become too similar, reducing their ability to distinguish between nodes. Additionally, GCN typically assumes a fixed graph topology, making it less adaptable to dynamic variations in node or edge features than inductive models.
As shown in
Figure 5, when processing two-hop heterogeneous graph data, the GCN uses a framework of “relation-specific decomposition, per-relation convolution, and summation aggregation”. Message passing is performed independently for edge 1 and edge 2, with the results from each relationship subsequently aggregated by summation. To balance the information propagation weights between BZG and BLG in the GNN model, the edge weights for Edge 1 and Edge 2 were set equally at 0.5. This explicit weighting configuration ensures that the predictive model concurrently encapsulates both inter-building spatial layouts and room-to-room topological relations during energy prediction.
For integrating edge features, the GCN maps the multidimensional features ( and ) of all edges into scalar weights, which are then incorporated into the propagation process.
2.3.2. GraphSAGE
GraphSAGE is an inductive GNN framework that generates node embeddings by sampling and aggregating features from the local neighborhood of a node. Unlike transductive models, it supports inductive learning, which allows effective generalization to previously new nodes or completely new graph that were not seen. Different aggregation methods, including mean, LSTM, and pooling, can be used to integrate information from neighboring nodes. The core formulation of GraphSAGE is defined as follows:
In this equation, is the feature vector of neighbor from the neighborhood set, , at the preceding layer, (). is the function employed to fuse neighborhood features into a unified vector. represents the learnable weight matrix, while is the nonlinear activation function, enabling the model to capture complex, nonlinear patterns.
GraphSAGE follows an inductive learning approach, meaning the model learns a generalized aggregator function rather than fixed embeddings for each node. However, its random sampling process introduces variability during training, which may affect the stability of convergence. Furthermore, aggregating over a sampled subset of neighbors can result in information loss, particularly when critical structural details are missing during the sampling phase.
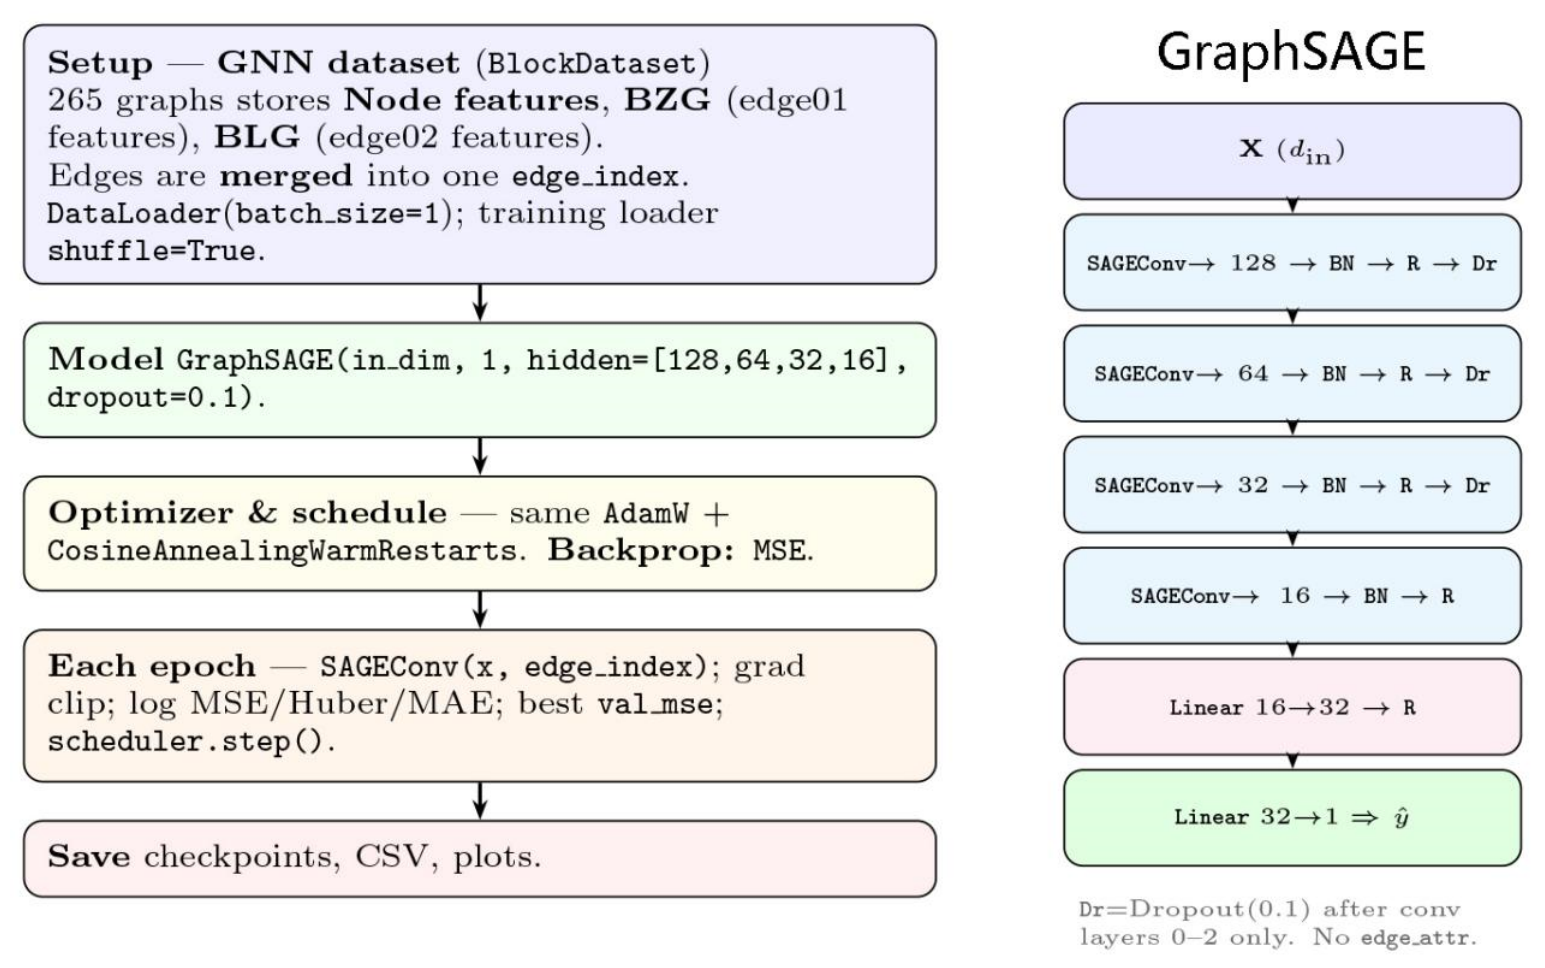
As shown in
Figure 6, GraphSAGE processes two-hop heterogeneous graph data using a framework like GCN, characterized by “relation-specific decomposition, per-relation convolution, and summation aggregation”. For integrating edge features, GraphSAGE similarly maps all edge features into scalar weights (the scalar weight of edge 1 and edge 2 are both 0.5), which are then incorporated into the message propagation process to modulate the influence of different neighboring types.
2.3.3. Graph Attention Network (GAT)
GAT improves the GCN framework by introducing a learnable attention mechanism that assigns adaptive weights to neighboring nodes, removing the need for predefined normalization based on node degrees. Rather than changing the fundamental “neighborhood aggregation” approach, GAT replaces fixed normalization with a learnable attention module. This advancement enables the model to adaptively assign importance to different neighbors based on the semantic content of their features.
To highlight this distinction, the aggregation method of GCN can be expressed as follows:
In contrast, the aggregation method for GAT is defined as follows:
In this mechanism,
represents attention weight. For a target node,
, and its neighbor,
, GAT first computes an attention score,
. Subsequently, a Softmax function is applied across the entire neighborhood,
, to normalize these scores, getting the final weights. The equations for
and
are as follows:
where LeakyReLU is the nonlinear activation function,
is a learnable attention weight vector used to evaluate the importance of concatenated features, and
is a learnable weight matrix for the linear transformation of node features. The ability of GAT to dynamically learn neighbor importance makes it particularly suitable for heterogeneous graphs with diverse node roles. Furthermore, attention weights provide inherent interpretability, enabling the visualization of influential spatial relationships. However, GAT is sensitive to noisy or spurious connections, which may distort the attention distributions.
As shown in
Figure 7, when processing two-hop heterogeneous data, GAT utilizes a multi-head attention mechanism that inputs the two edge attributes into the model by independent relationship channels. These attributes directly influence the attention weights (the attention weight of edge 1 and edge 2 are both 0.5), allowing for a more refined integration of structural and geometric information.
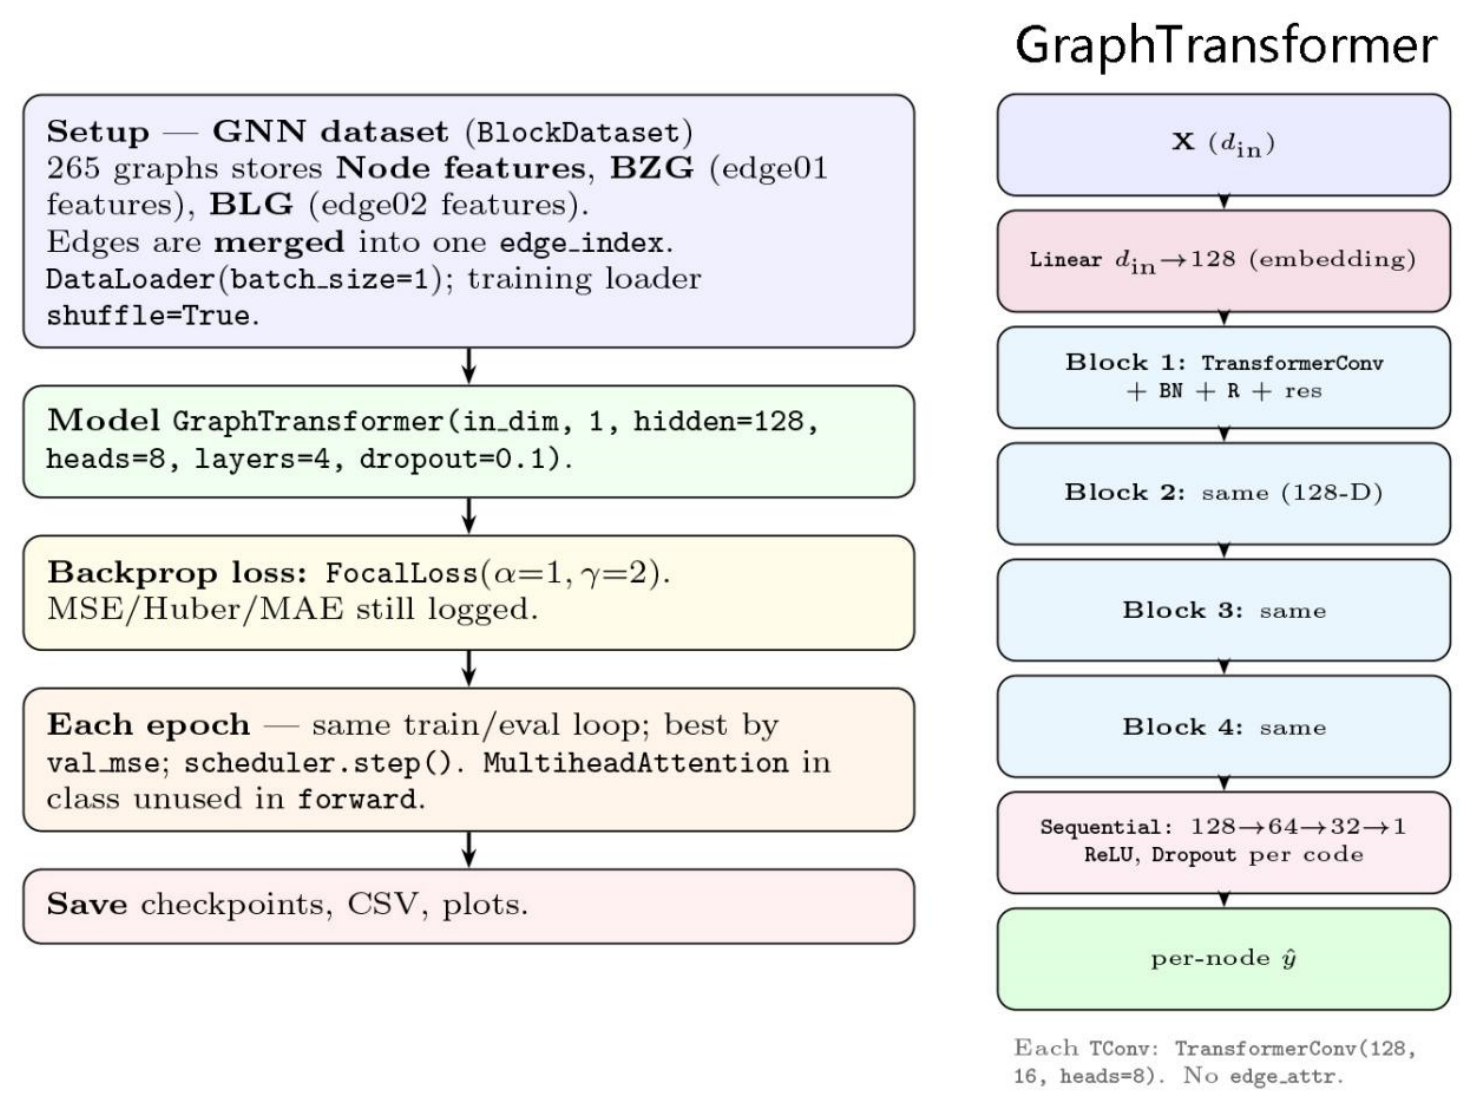
2.3.4. GraphTransformer
In the GraphTransformer architecture, given an input graph with node features
, each node is first projected into a shared hidden space via a linear embedding layer:
The model stacks
Transformer-based convolutional layers. At the
-th layer, for each attention head,
, the node representation,
, is linearly projected into query (
), key (
), and value (
) vectors:
The attention coefficient for an edge (
) is computed as a scaled dot-product followed by a Softmax normalization over the neighborhood,
:
The aggregated message for head
is then derived as follows:
The multi-head output is obtained by concatenating
across all heads. Each layer further incorporates Batch Normalization (BN) and a residual connection, followed by a ReLU nonlinearity:
where
denotes the ReLU activation function. After
layers, the final node embeddings,
, are passed through a lightweight feed-forward network (FFN) to produce the scalar regression output,
, for each node.
As shown in
Figure 8, GraphTransformer follows the established framework for processing two-hop heterogeneous graph data. Regarding edge feature integration, similar to GAT, GraphTransformer uses a multi-head attention mechanism to input the two edge features through independent relationship channels, where these features directly influence the calculation of attention weights to capture complex spatial relationships. The attention weights for Edge 1 and Edge 2 are uniformly set as 0.5 to sustain a relatively balanced information propagation paradigm between the BZG and BLG domains, thereby ensuring equalized feature contributions to the final GNN prediction outcomes.
2.4. GNN Model Train and Evaluation
Model training and analysis were executed in a Python 3.12 environment using a computer comprised of an AMD Ryzen 9 7950X 16-core CPU, an NVIDIA GeForce RTX 4070 Ti GPU, and 64 GB of RAM. Before model training, hyperparameter optimization studies were conducted on the same computer to guarantee optimal configuration and architectural convergence for each GNN model.
2.4.1. Hyperparameter Optimization
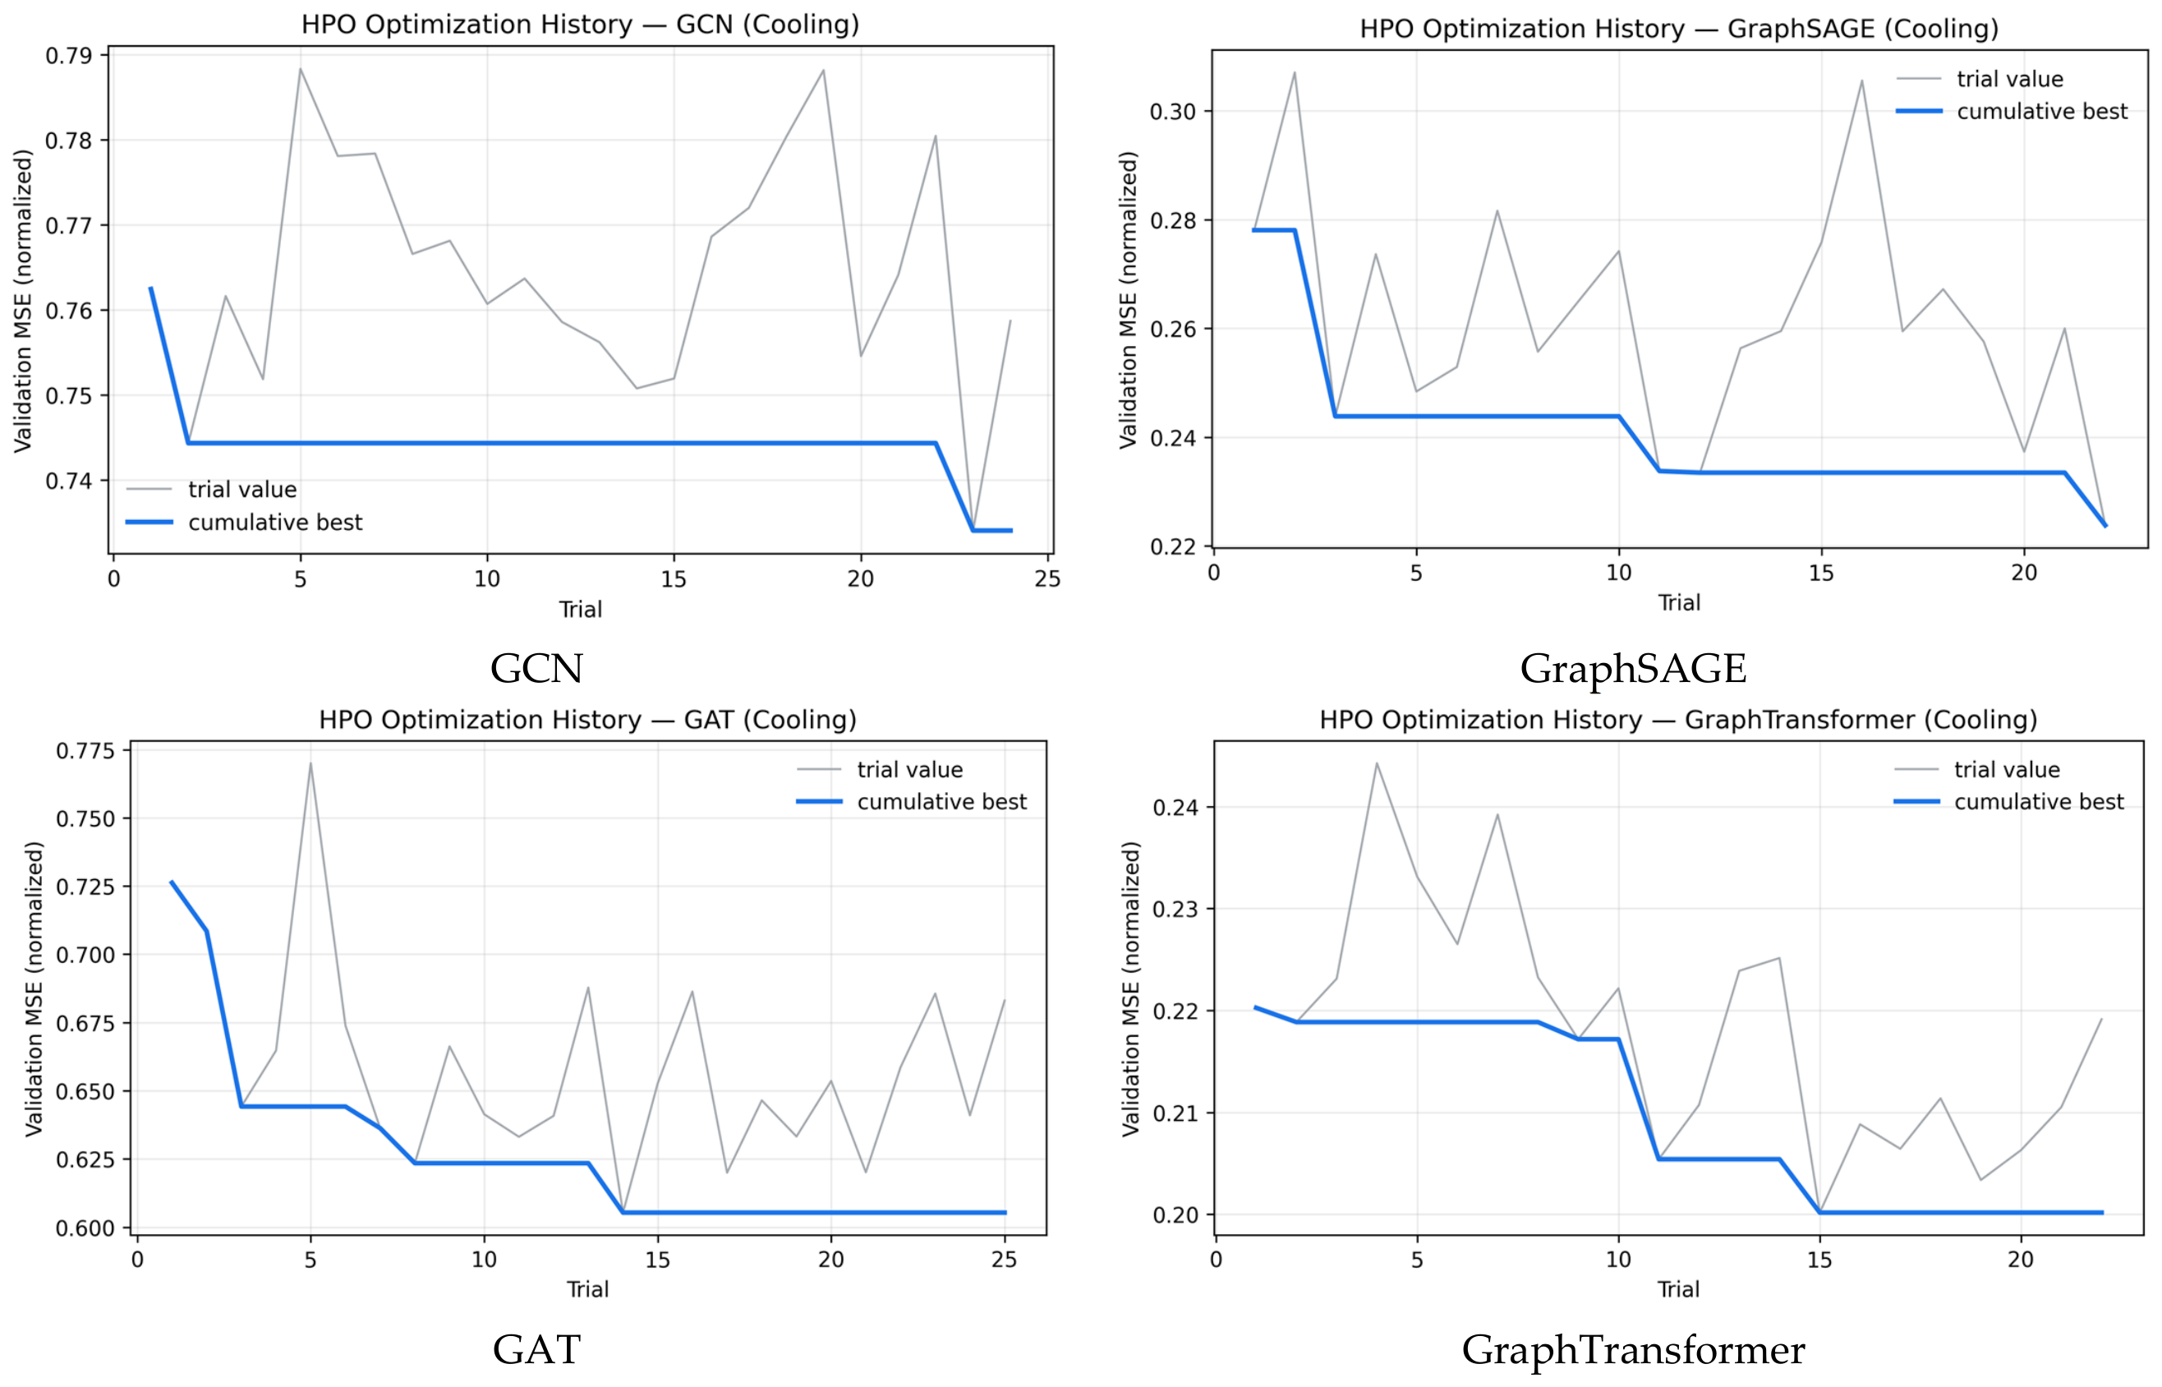
Table 9 summarizes the baseline hyperparameter settings of the four GNN architectures. To improve the model performance, automated hyperparameter optimization (HPO) was conducted for each algorithm using the Optuna framework [
67]. The HPO process aimed to minimize the MSE loss as the objective function, while maintaining the train/validation split consistently to ensure fair comparison among the models.
For each GNN architecture, Optuna executed 30 independent trials. In every trial, the model was trained for 200 epochs (in total, 6000 training epochs for HPO), and the trajectory of the MSE loss on the validation set was monitored. The minimum MSE loss achieved within each trial was then returned as the objective value for optimization.
The specified search space (
Table 10) includes key hyperparameters, such as optimizer settings (learning rate and weight decay), network size (number of layers, hidden units), and regularization methods (dropout). For attention-based architectures (GAT and GraphTransformer), the number of attention heads was also integrated into the search space. After the HPO process was completed, the best hyperparameter settings were selected to perform the final training of the surrogate models.
2.4.2. GNN Training and Evaluation
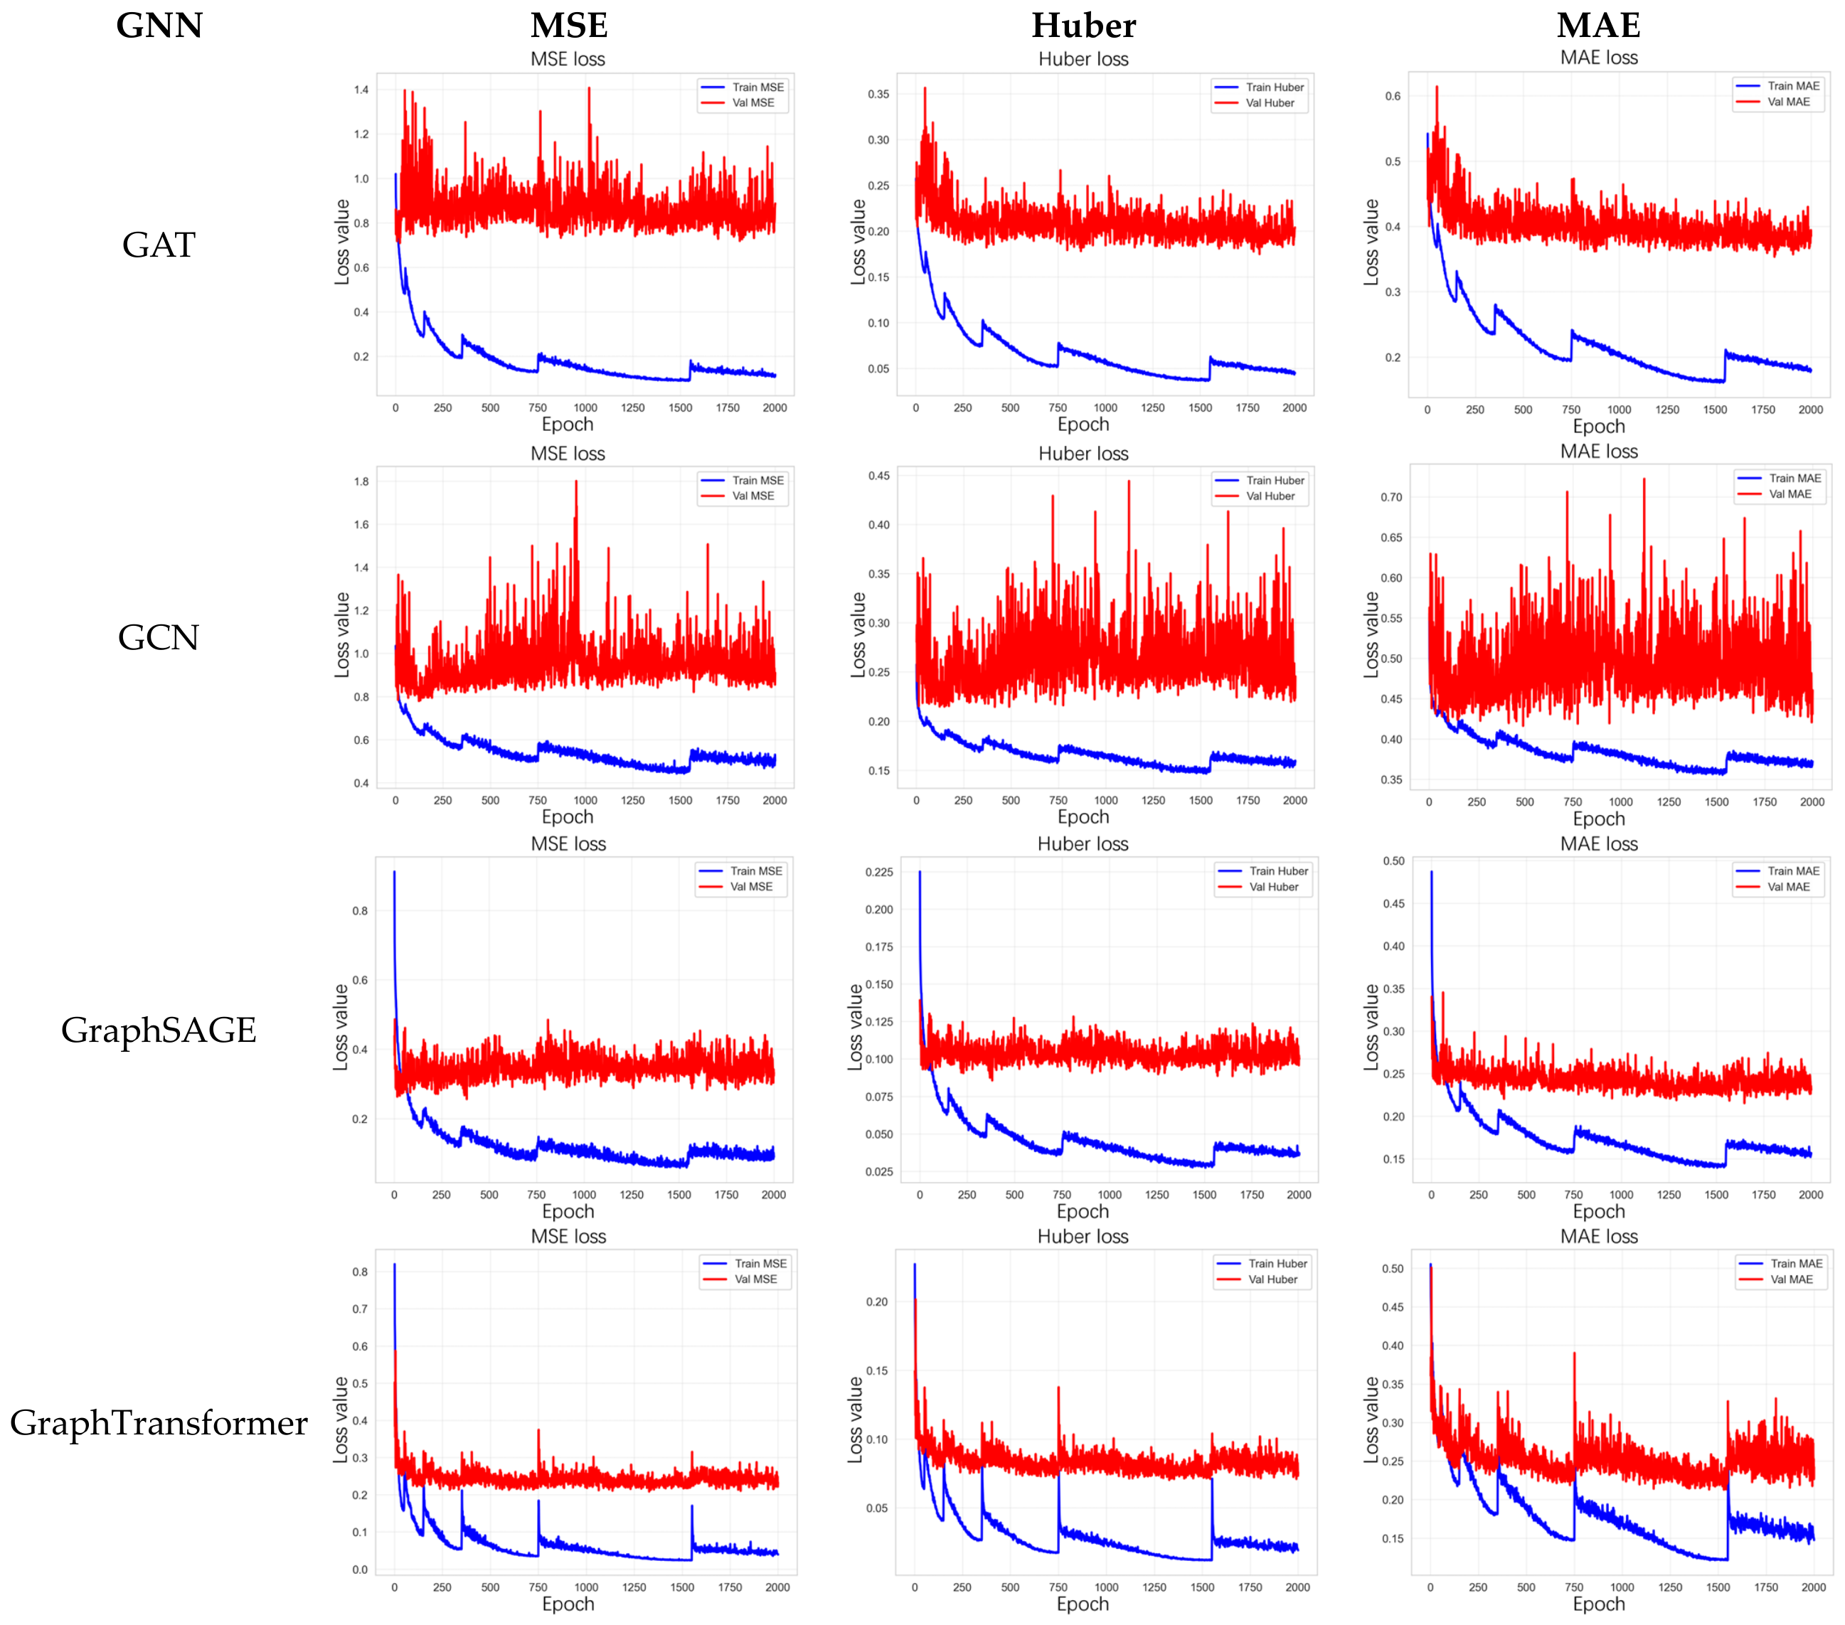
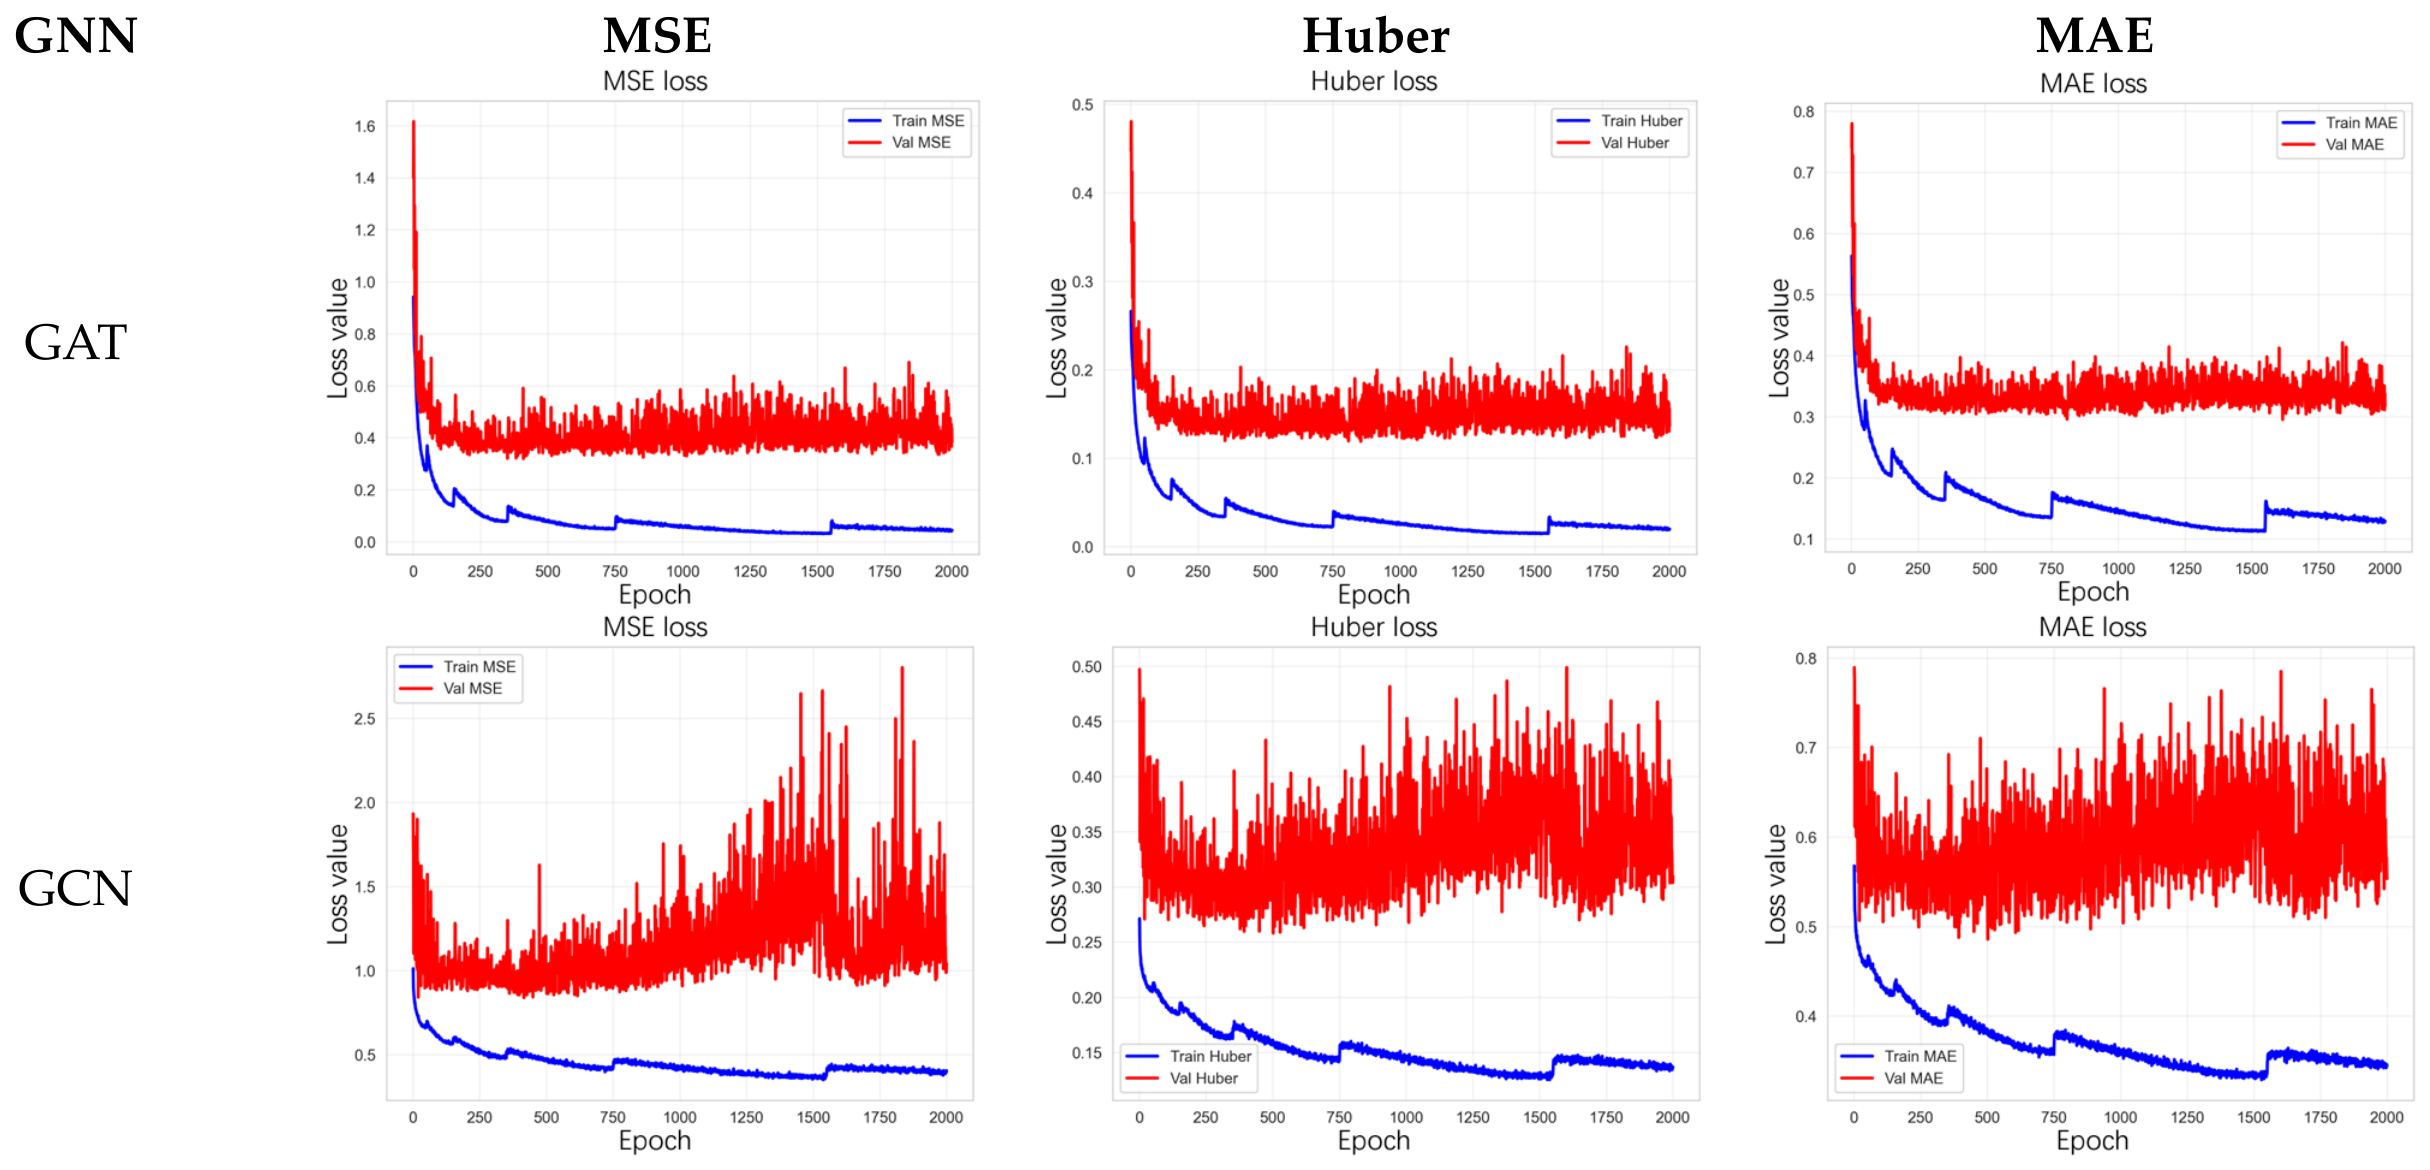
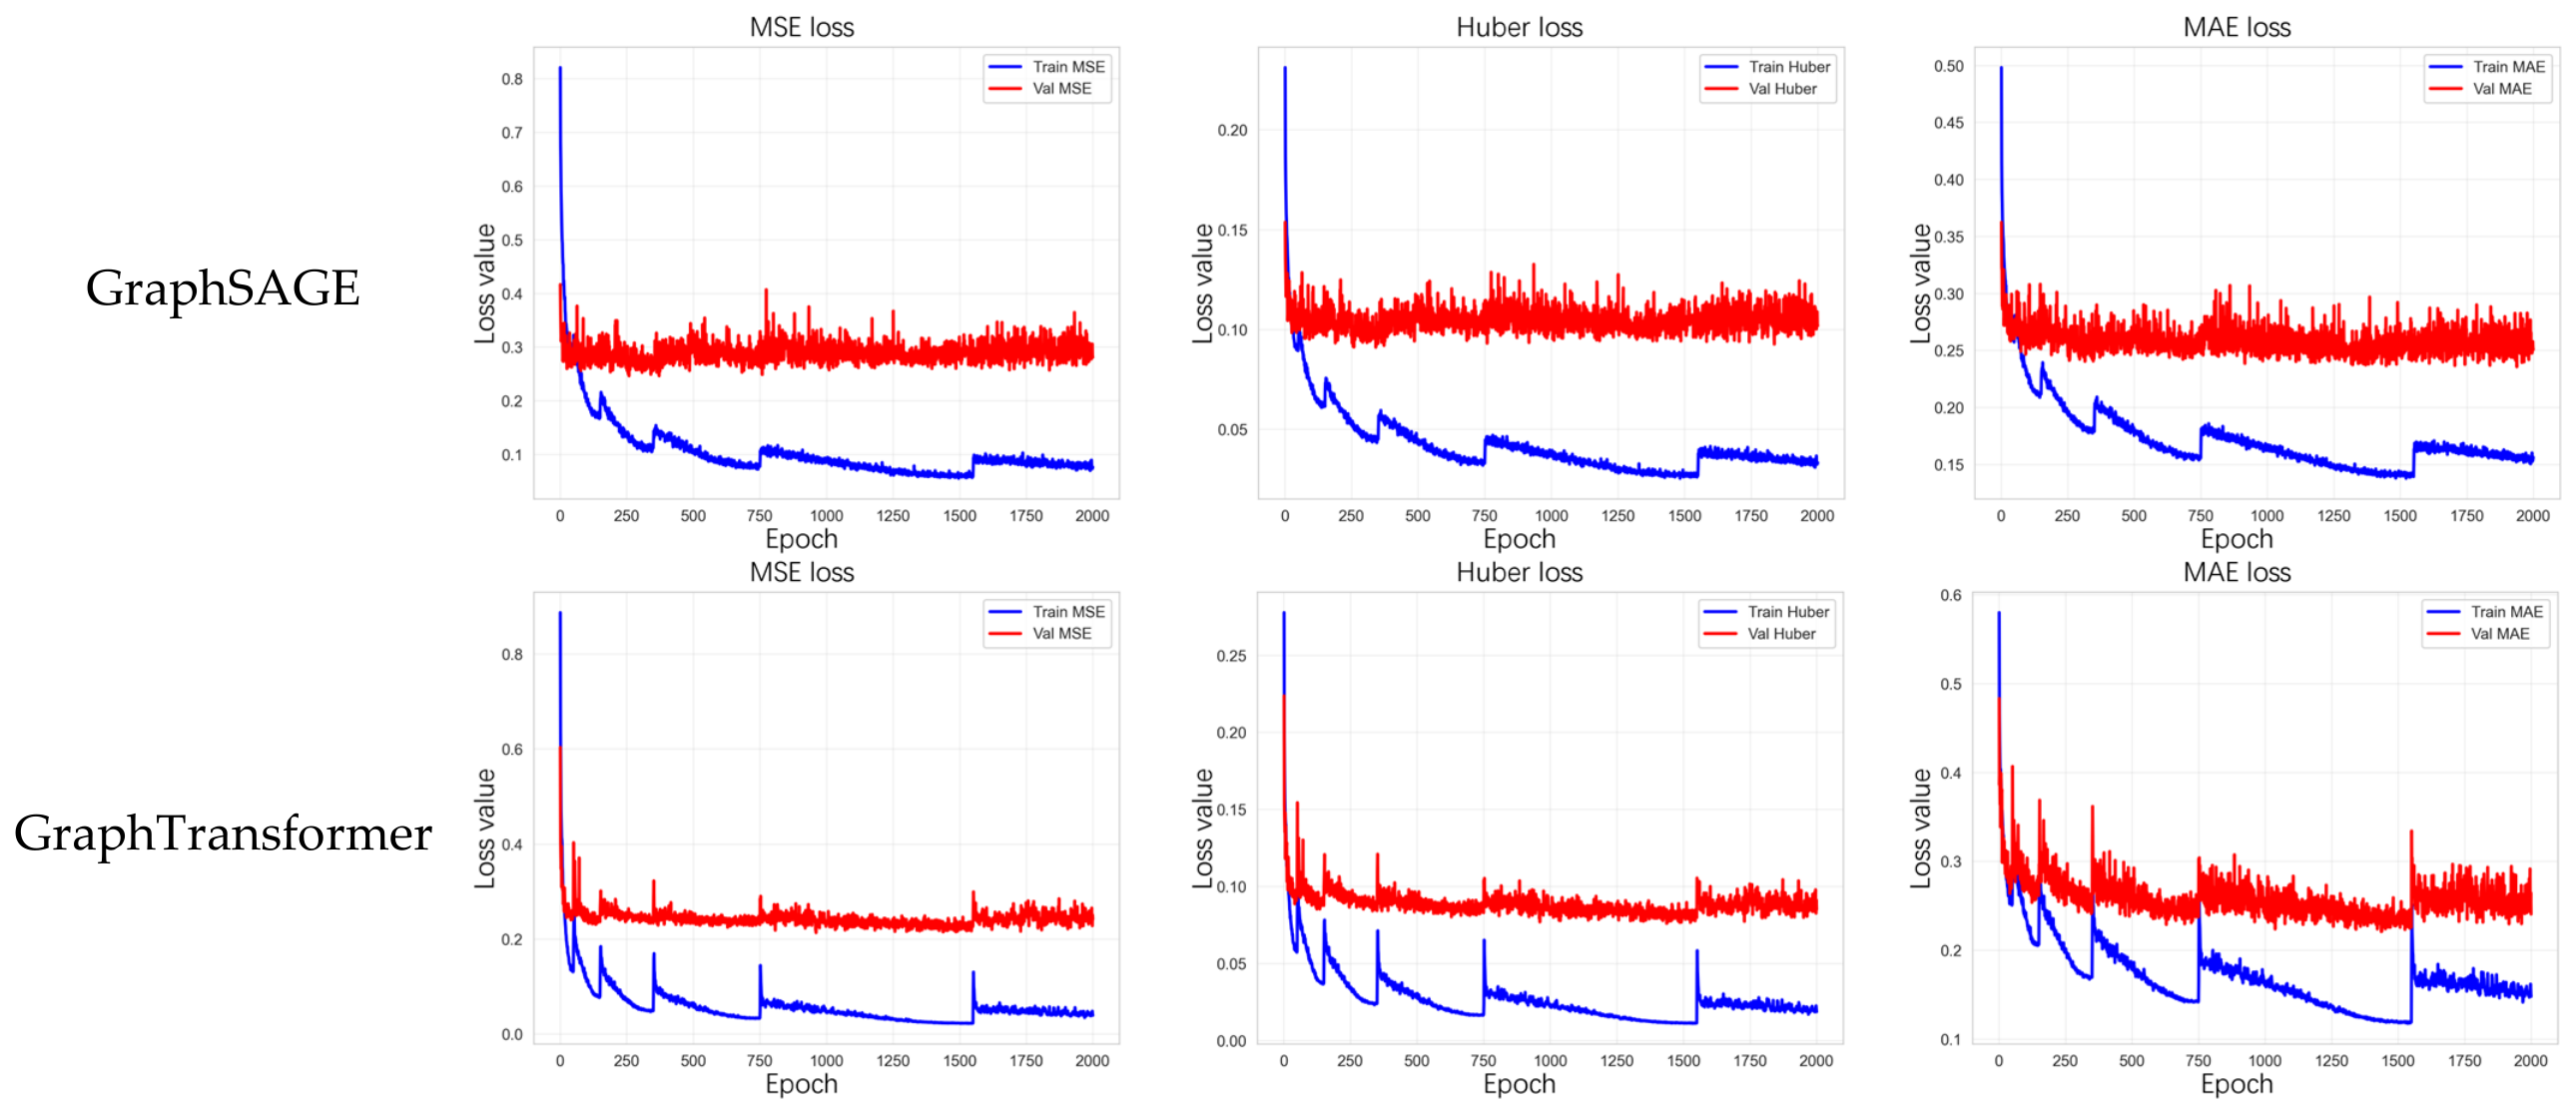
The training process was executed in mini batches, with model weights updated based on gradients calculated at each step. To ensure robustness and convergence, a multi-objective loss strategy was used in this study. The main loss function for back-propagation was Mean Squared Error Loss (), which aimed to maintain overall predictive accuracy. At the same time, Huber loss () and Mean Absolute Error Loss () were tracked. enhances the model’s resilience to outliers, while provides a metric for error interpretation. The optimal model was identified at the bottom of the loss curve on the validation dataset.
For each node,
, in the GNN, the model generates a prediction,
, where
represents the simulated ground truth. The equations for
and
are as follows:
In terms of
, let
denote the residual for each sample, defined as
. With the threshold,
, set to 1,
is defined as follows:
The optimal GNN energy prediction model was selected based on the loss function trajectories observed during the training of the four algorithms. To evaluate accuracy and generalizability, the 10% independent dataset, which was not used during training, was used for final verification. Specifically, the optimal GNN model was used to predict the and for the nodes in the dataset, using their graphs and features.
The predictive accuracy was quantified using the Coefficient of Determination (
), which evaluates the GNN-predicted values against the simulated ground truth:
where
represents the mean simulated value of all nodes.
2.5. GNNExplainer
The “black-box” character of the GNN model significantly limits model interpretability and decreases its trustworthiness in practical applications. To better understand how GNN models make decisions in energy prediction at the urban-block level, this research applies the GNNExplainer algorithm to perform a post hoc interpretability analysis on the trained model. By quantifying the importance of node features and by visualizing the information passing pattern, this study systematically uncovers the key factors and interactions driving the model’s predictions, thereby enhancing both transparency and validity of model.
GNNExplainer is a perturbation-based interpretation method that identifies the most influential node features and edges by learning the differentiable masks. It optimizes the following objective function:
where
represents the prediction fidelity loss, which minimizes the negative log-likelihood under the candidate sub-graph,
, and feature subset,
, to ensure consistency between the generated explanation and the original model prediction. The terms
and
are
regularization terms that are applied to the feature mask,
, and adjacency mask,
, respectively;
and
control the sparsity strength to promote concise explanations. Furthermore,
serves as an entropy-based regularizer, where
denotes the entropy of the mask distribution; this term prevents the over-concentration of importance on a limited number of elements, thereby enhancing the diversity and robustness of the explanation. The specific hyperparameter configurations for GNNExplainer are listed in
Table 11.
By jointly optimizing and , GNNExplainer identifies the most critical sub-graph, , and feature set, , for predicting the target, . To comprehensively evaluate the quality of these explanations, this study employs a hybrid assessment framework:
This integrated evaluation strengthens the credibility and practical relevance of the interpretability results.
2.6. GNN Explainer Robustness Analysis and Ablation Study
To evaluate the GNN structural efficacy and GNNExplainer stability, ablation and robustness experiments were conducted. The ablation study sequentially removes core components and features to isolate the independent contributions of graph and node attributes. Robustness is evaluated by quantifying the stability of GNNExplainer.
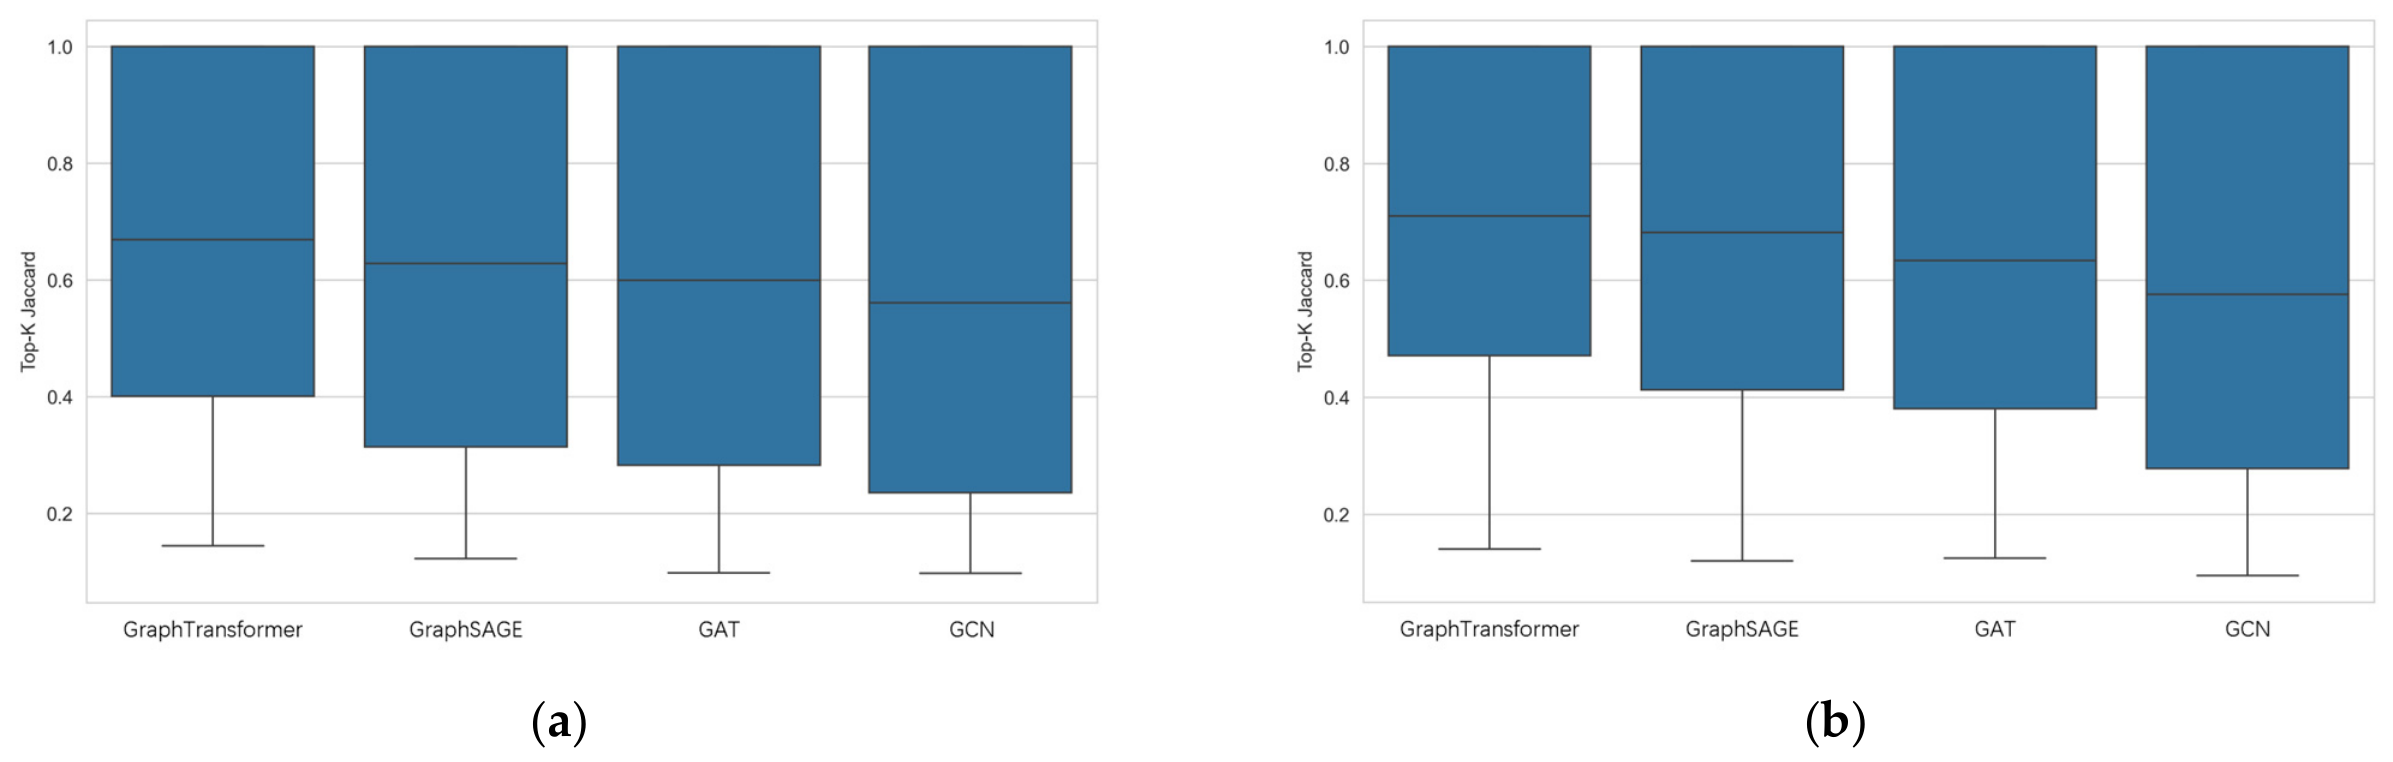
Specifically, each GNN model was executed across 15 independent random seeds using GNNExplainer, and the reproducibility of the edge-level attributions was measured using the Jaccard similarity index across the top 10% highest-ranked edges.
For the ablations, five independent sub-datasets (Datasets 01–05, configured as shown in
Table 12) were generated. These new GNN models, alongside the full-graph models, were used to predict
and
, using Root Mean Square Error (
) to determine the dependency on specific graph configurations of each GNN network.
4. Discussion
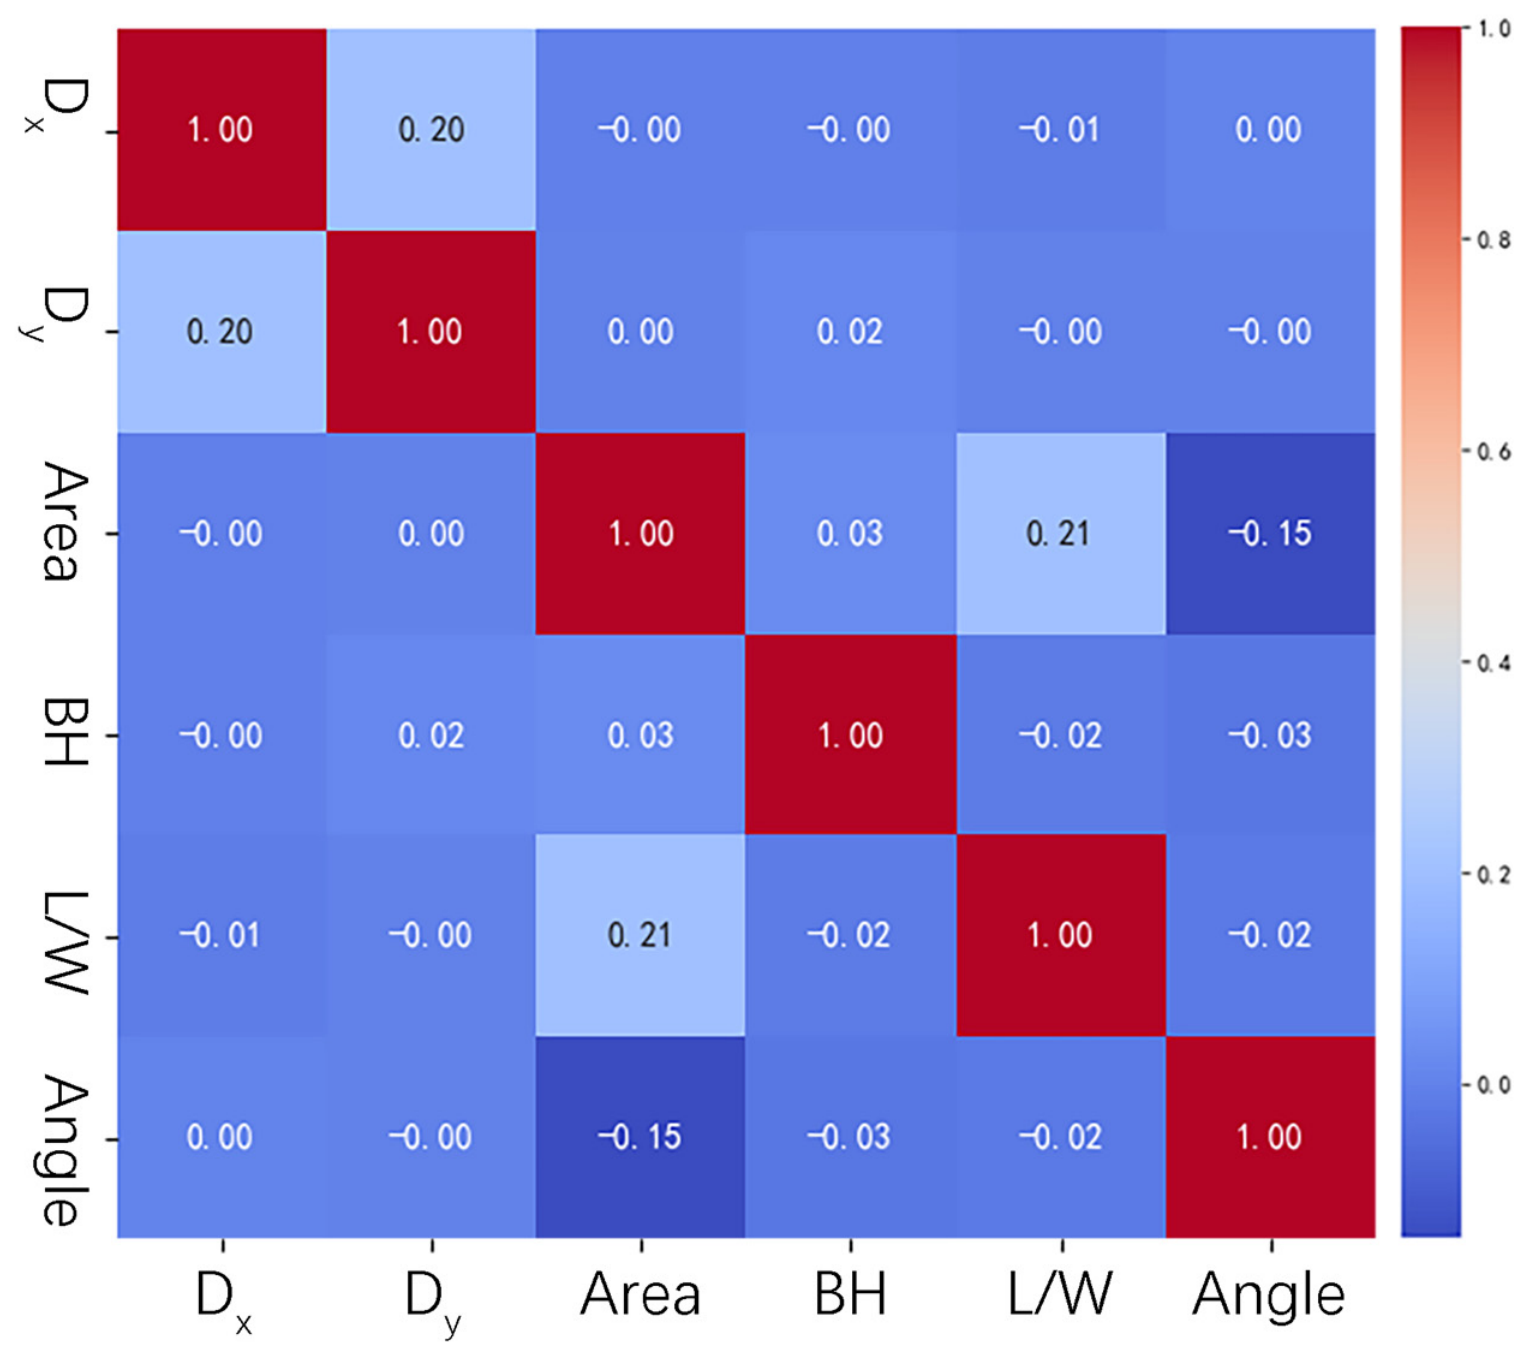
Before the GNN interpretability analysis, this study made a correlation analysis of the features for each node. As shown in
Figure 19, there is no strong correlation among the six features of the nodes.
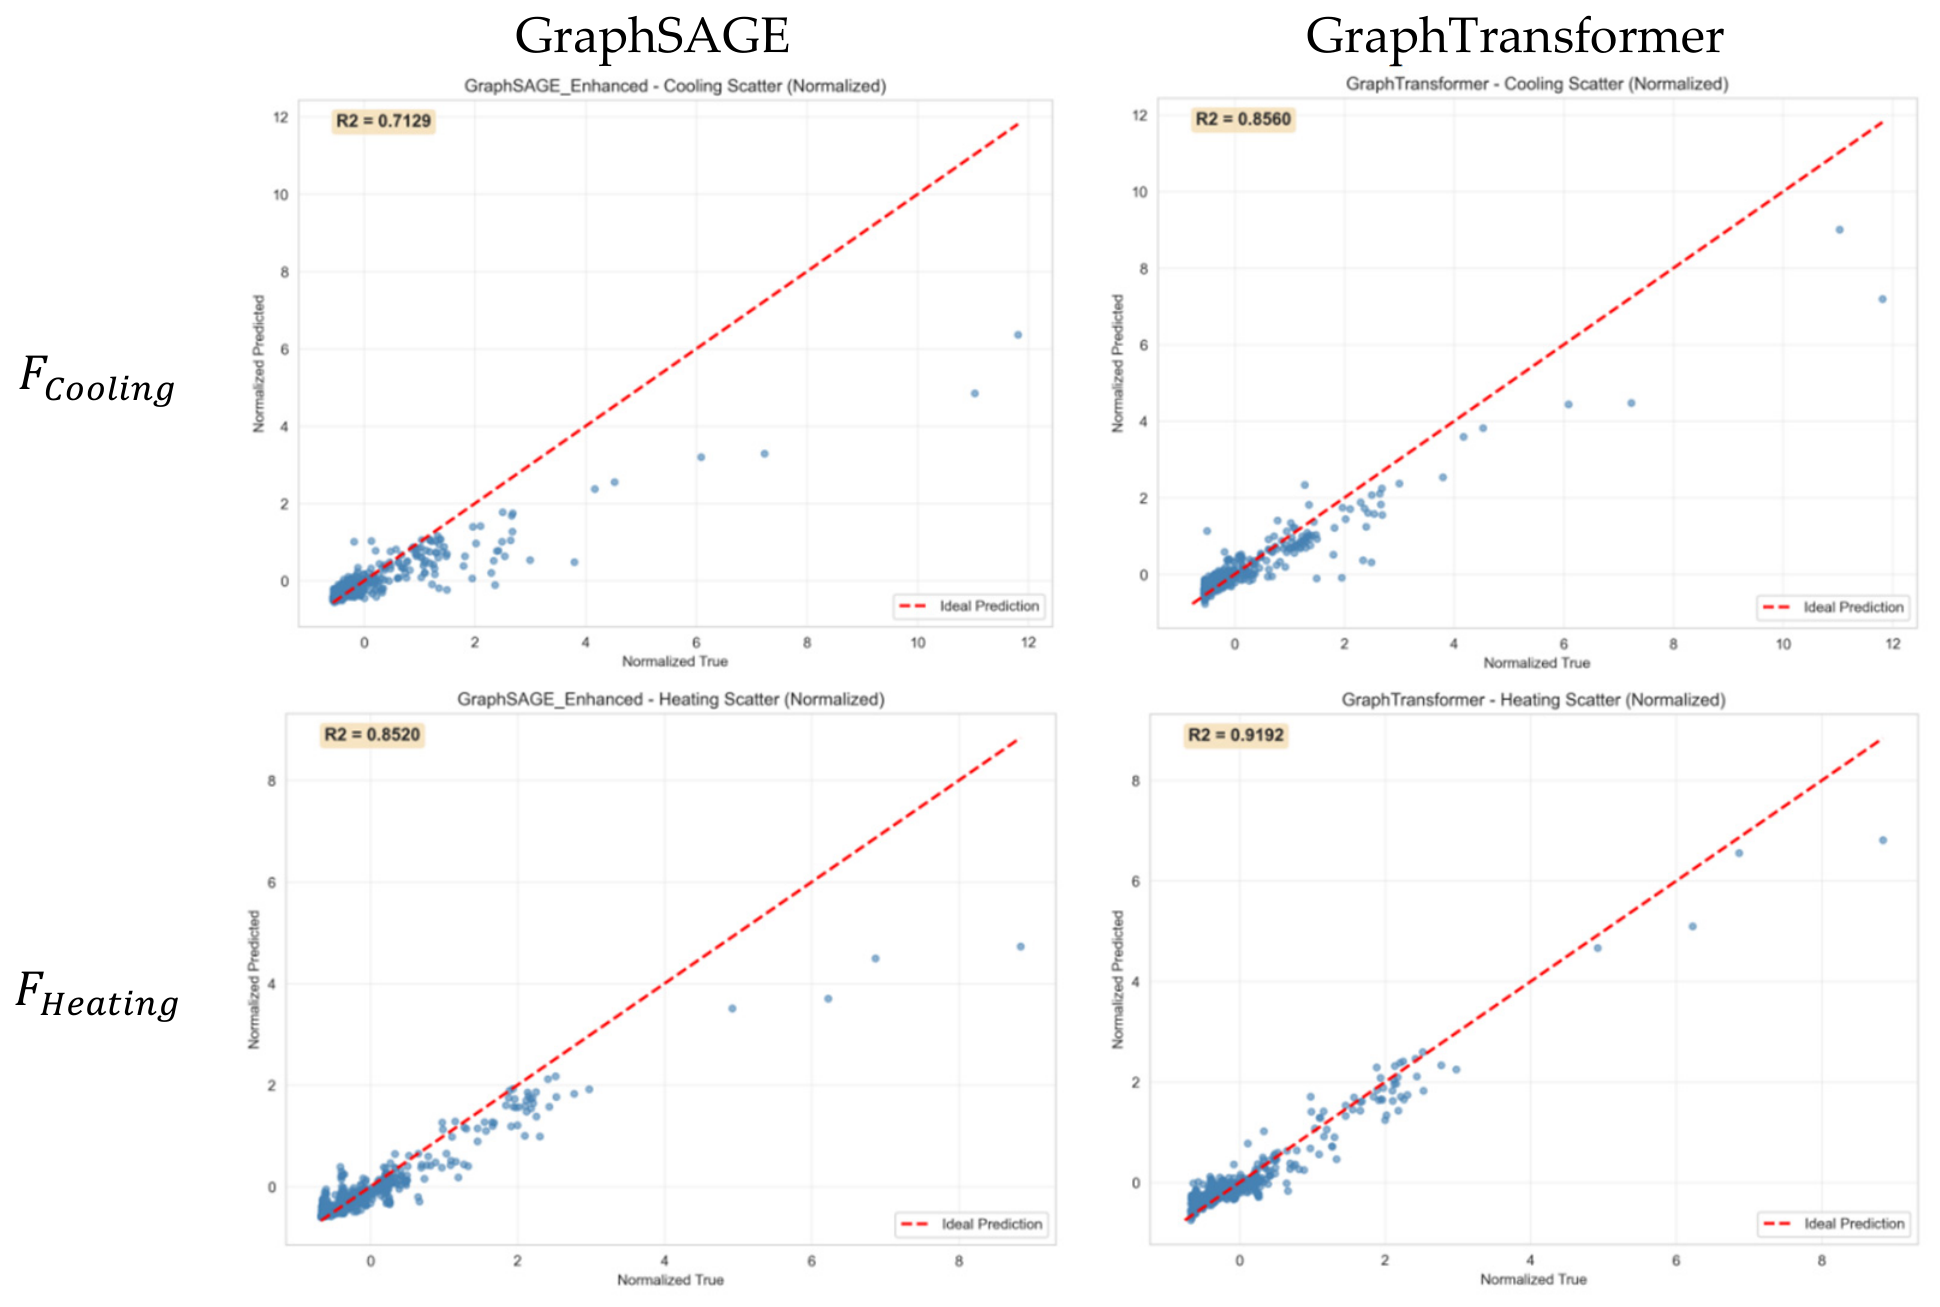
To show the operational mechanisms of the GNN predictive models, this study used GNNExplainer to perform a comparative analysis of the GraphSAGE and GraphTransformer models. This section explores the prediction logic of the surrogate models through the node feature importance and edge-level signal-propagation patterns.
4.1. Node Feature Importance Analysis
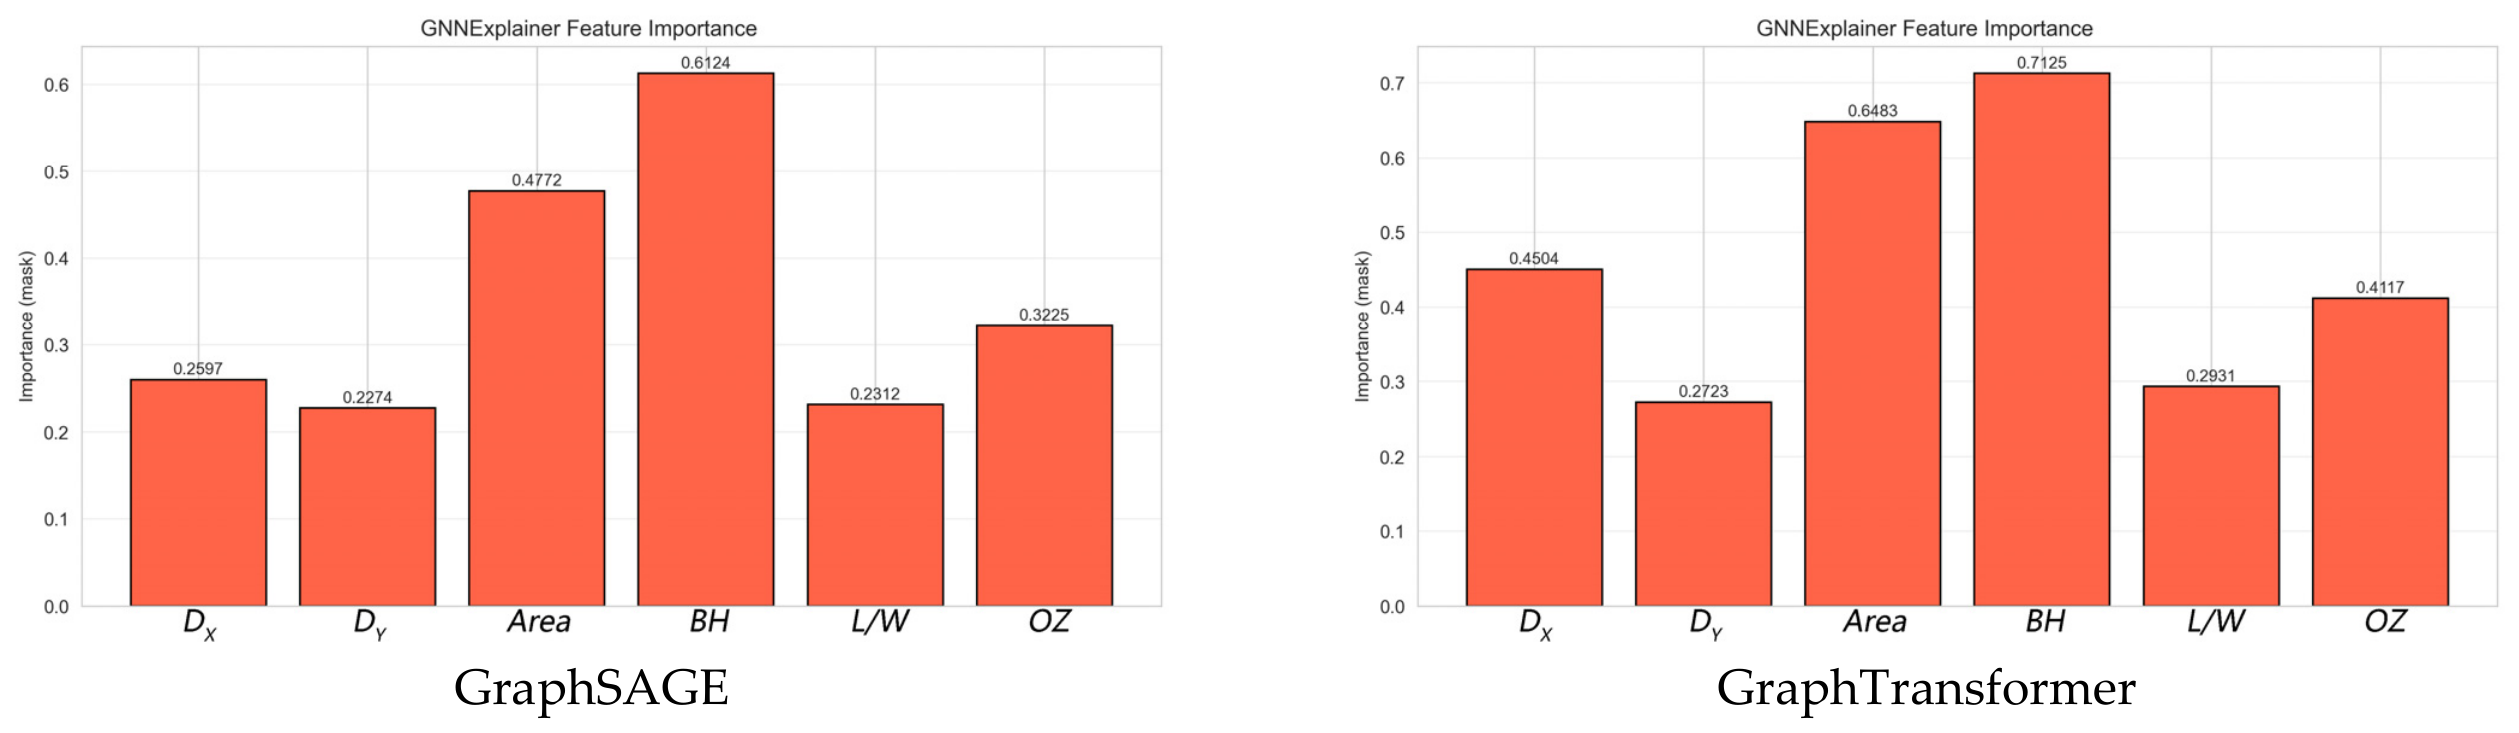
As shown in
Figure 20,
(0.6124 for GraphSAGE and 0.7125 for GraphTransformer) and
(0.4772 for GraphSAGE and 0.6483 for GraphTransformer) are the most critical node features in
prediction. Physically, increased building height correlates with a lower shape factor, which minimizes the envelope-to-volume ratio and subsequently reduces unit-area heat-gain and cooling-system energy consumption. Conversely, a larger floor area necessitates higher cooling capacities and extended operational hours to maintain cooling-system setpoint, thereby increasing cooling-system energy consumption. The
(representing east–west positioning) exhibited high importance in the GraphTransformer model (0.4504). This suggests that the model more effectively captures how east–west direction building layout distribution influences inter-building shading [
20] and the subsequent cooling energy demand. Finally,
was identified as a critical feature (0.3225 and 0.4117), confirming that GNN algorithms prioritize the orientation of facade relative to the south, where minimized angles with north direction mean higher solar gains.
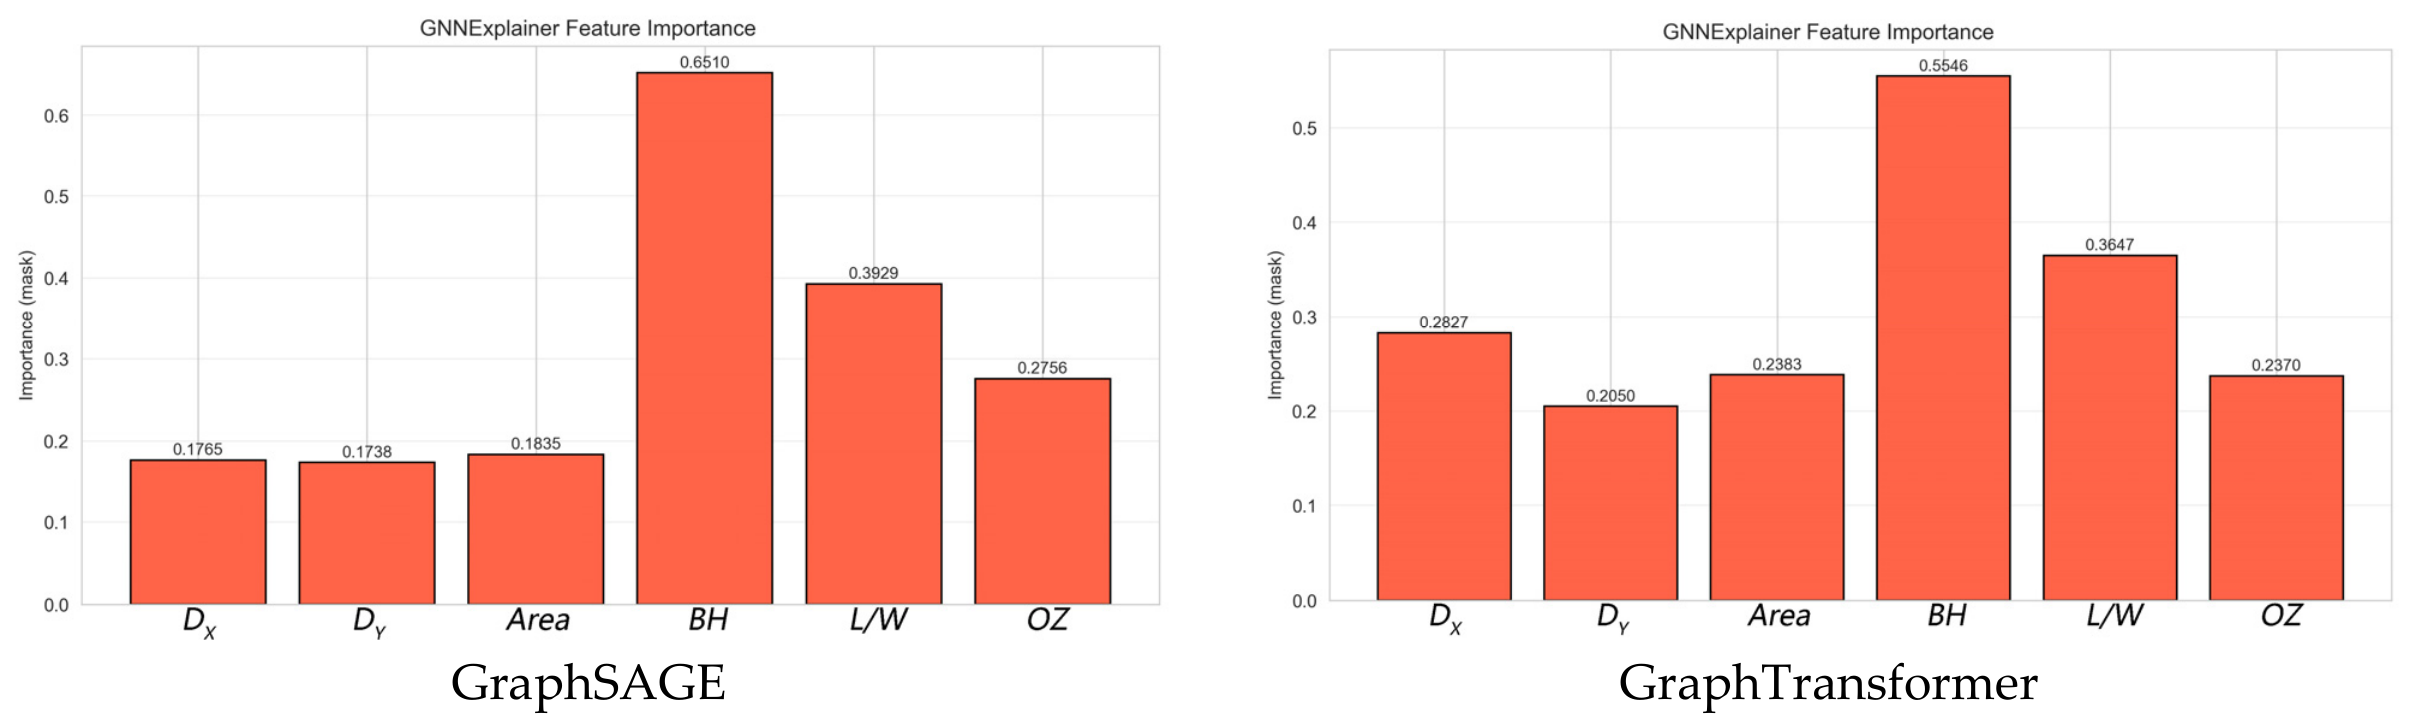
As shown in
Figure 21, both models emphasized
(0.651 and 0.576) and
(0.393 and 0.372) as key indicators in
prediction. Like
, an increased height reduces the shape factor and unit-volume heat loss, thereby decreasing
. A higher
increases the exposure surface area of buildings, thereby accelerating heat dissipation and increasing
. Furthermore,
is also an important feature in GraphTransformer for
prediction. This suggests that the model more effectively captures how east–west direction building layout distribution influences inter-building shading and the subsequent heating energy demand.
In summary, this study identifies , , , and as the important features governing urban block energy consumption. These indicators exhibit a significant coupling with the “hot-summer and cold-winter” climate characteristics of Wuhan:
Scale effect: and describe total building volume and envelope surface area. Under the extreme summer-cooling and winter-heating demands of Wuhan, HVAC loads positive with the building volume.
Solar shading: and describe inter-building shading dynamics and solar heat gain. During Wuhan’s high-radiation summer, elevated and values maximize individual envelope exposure while simultaneously generating shading that effectively reduces the summer cooling load and increases the winter heating load of neighborhood buildings. Furthermore, reflects the longitudinal positioning of buildings, fundamentally altering the penetration of southern solar radiation into the block. This dynamic trade-off between summer shading and winter heat gain establishes the core value of morphological optimization in hot-summer and cold-winter zones.
4.2. Edge Propagation and Message-Passing Patterns
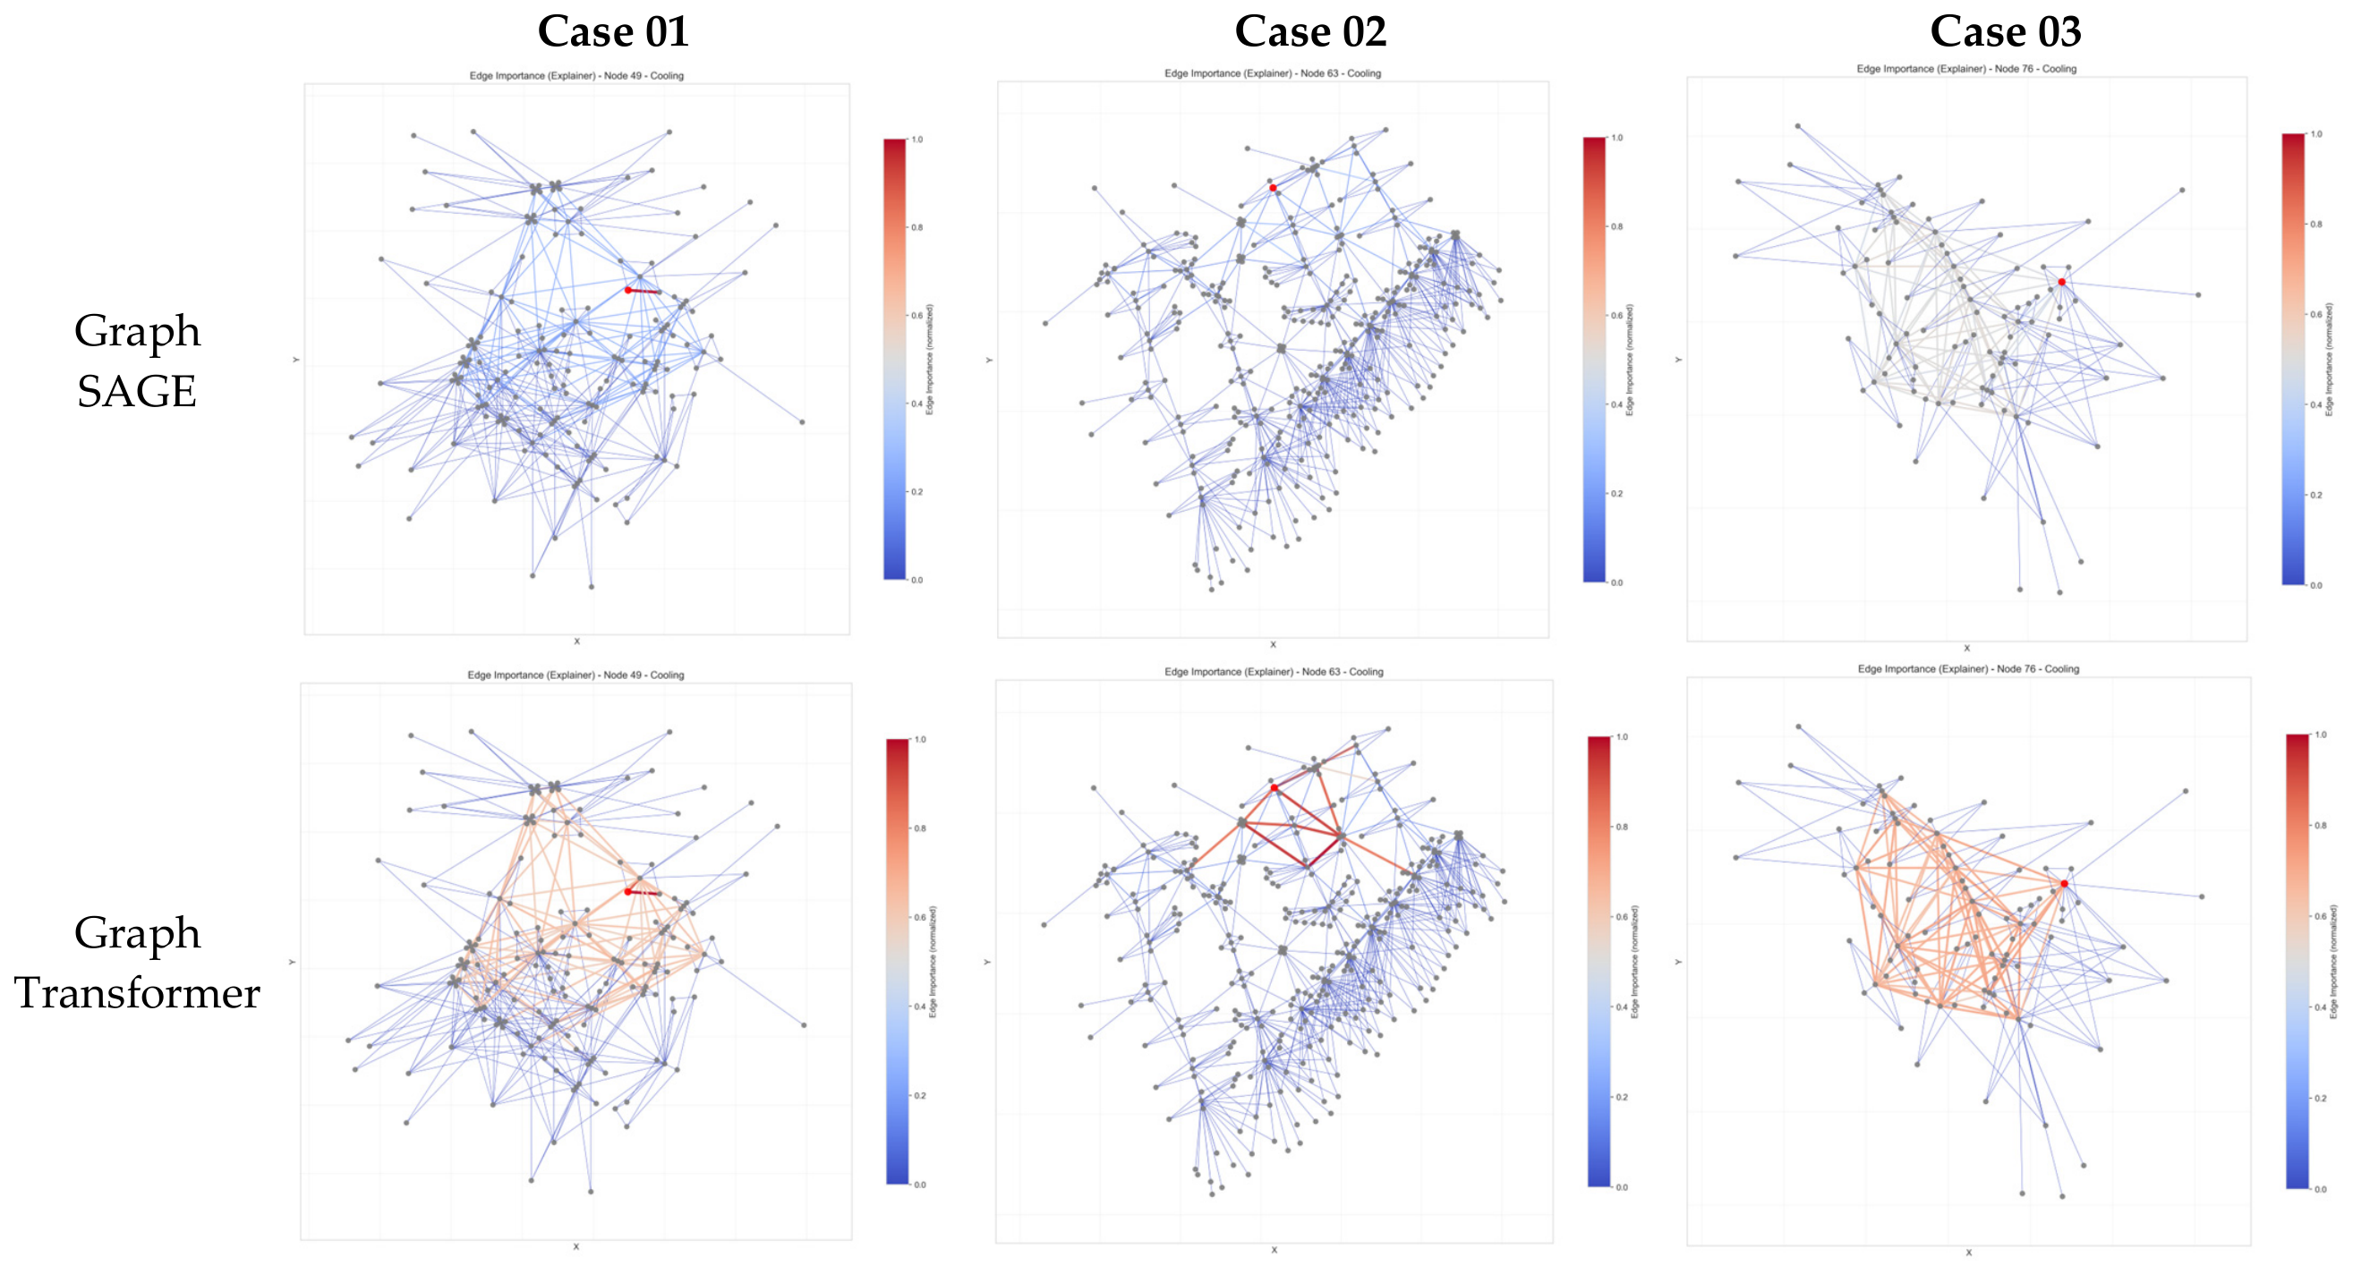
As shown in
Figure 22, the visualization of the explanation graphs for
prediction reveals fundamental differences in how these algorithms identify urban topology:
Case 1: For the target node prediction, GraphSAGE used only a single adjacent edge. In contrast, GraphTransformer used a substantial cluster of edge relationships from the southwestern direction, capturing a broader spatial context.
Case 2: GraphSAGE failed to incorporate surrounding edge relationships. Conversely, GraphTransformer successfully identified and used critical edges located to the south of the target node, reflecting the impact of southern solar shading.
Case 3: Although both models recognized southwestern edge influences, GraphTransformer assigned significantly higher influence weights to these connections.
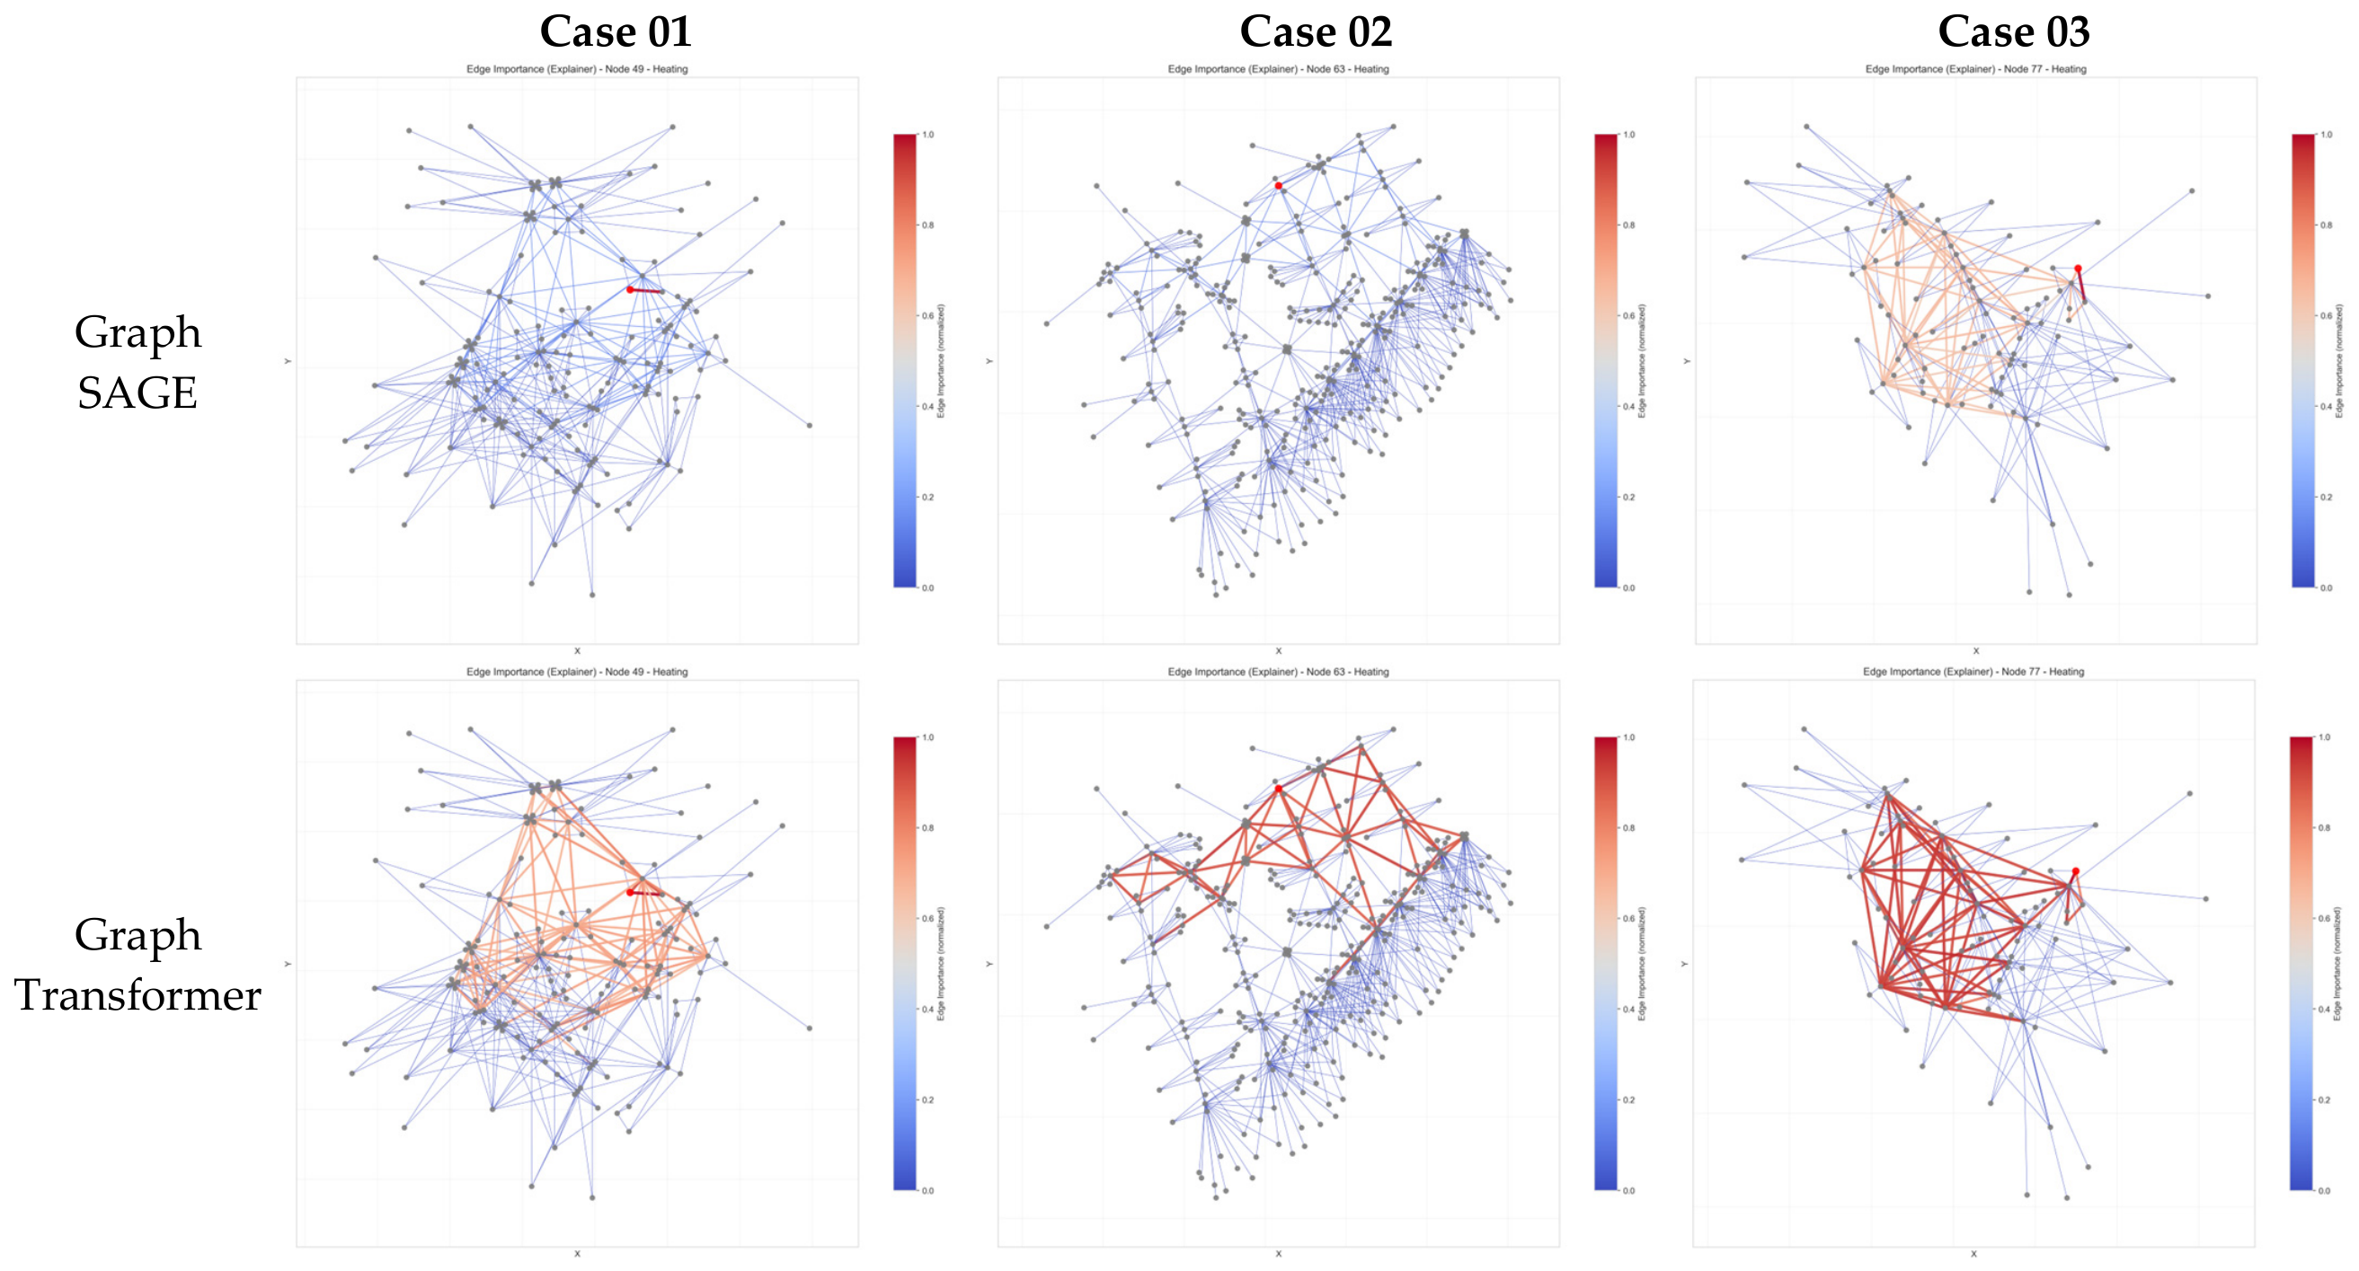
As shown in
Figure 23, the visualization of the explanation graphs for
prediction reveals fundamental differences in how these algorithms identify urban topology:
Case 1: GraphSAGE focused on a single adjacent signal, while GraphTransformer incorporated extensive signals from the surroundings and the southwest.
Case 2: GraphSAGE failed to incorporate surrounding edge relationships, whereas GraphTransformer successfully used extensive southern edge signals.
Case 3: Both models utilized similar signals, but GraphTransformer demonstrated a higher sensitivity to these topological inputs by increased signal weights.
In summary, the two algorithms exhibit a shared reliance on and as core indicators. However, a significant difference exists in their utilization of spatial context: GraphTransformer uniquely incorporates as a critical node feature and consistently uses southward and westward edge signals to inform its predictions. This suggests that GraphTransformer possesses a better ability to internalize the physical shading logic in urban layouts than GraphSAGE.
4.3. GNNExplainer Stability Analysis
As shown in
Figure 24, the post hoc explanation stability of GNNExplainer across both
and
exhibits a highly consistent architectural hierarchy, ordered as follows: GraphTransformer > GraphSAGE > GAT > GCN.
Notably, the explanation reliability for all models scales is slightly higher in , with the GraphTransformer reaching a peak median Jaccard similarity of 0.71 compared to (0.67). This cross-seasonal consistency establishes that the multi-head self-attention mechanism within the GraphTransformer inherently extracts more deterministic, invariant edge-level structural features that remain resilient against random initialization seeds, thereby providing significantly more trustworthy interpretations for building energy prediction than traditional localized message-passing networks.
4.4. GNN Ablation Study
To evaluate the structural and feature dependencies of the GNN predictive models, four GNN algorithms were trained on five independent ablation datasets, and their performance was comparatively analyzed against the optimized baseline models trained on the fully GNN datasets. Based on feature analysis by GNNExplainer, and were identified as the important features for , whereas and are the primary features for . Consequently, the feature-based ablation datasets were created: Dataset 03 was generated by removing Area for and L/W for , while Dataset 04 was created by removing for both scenarios.
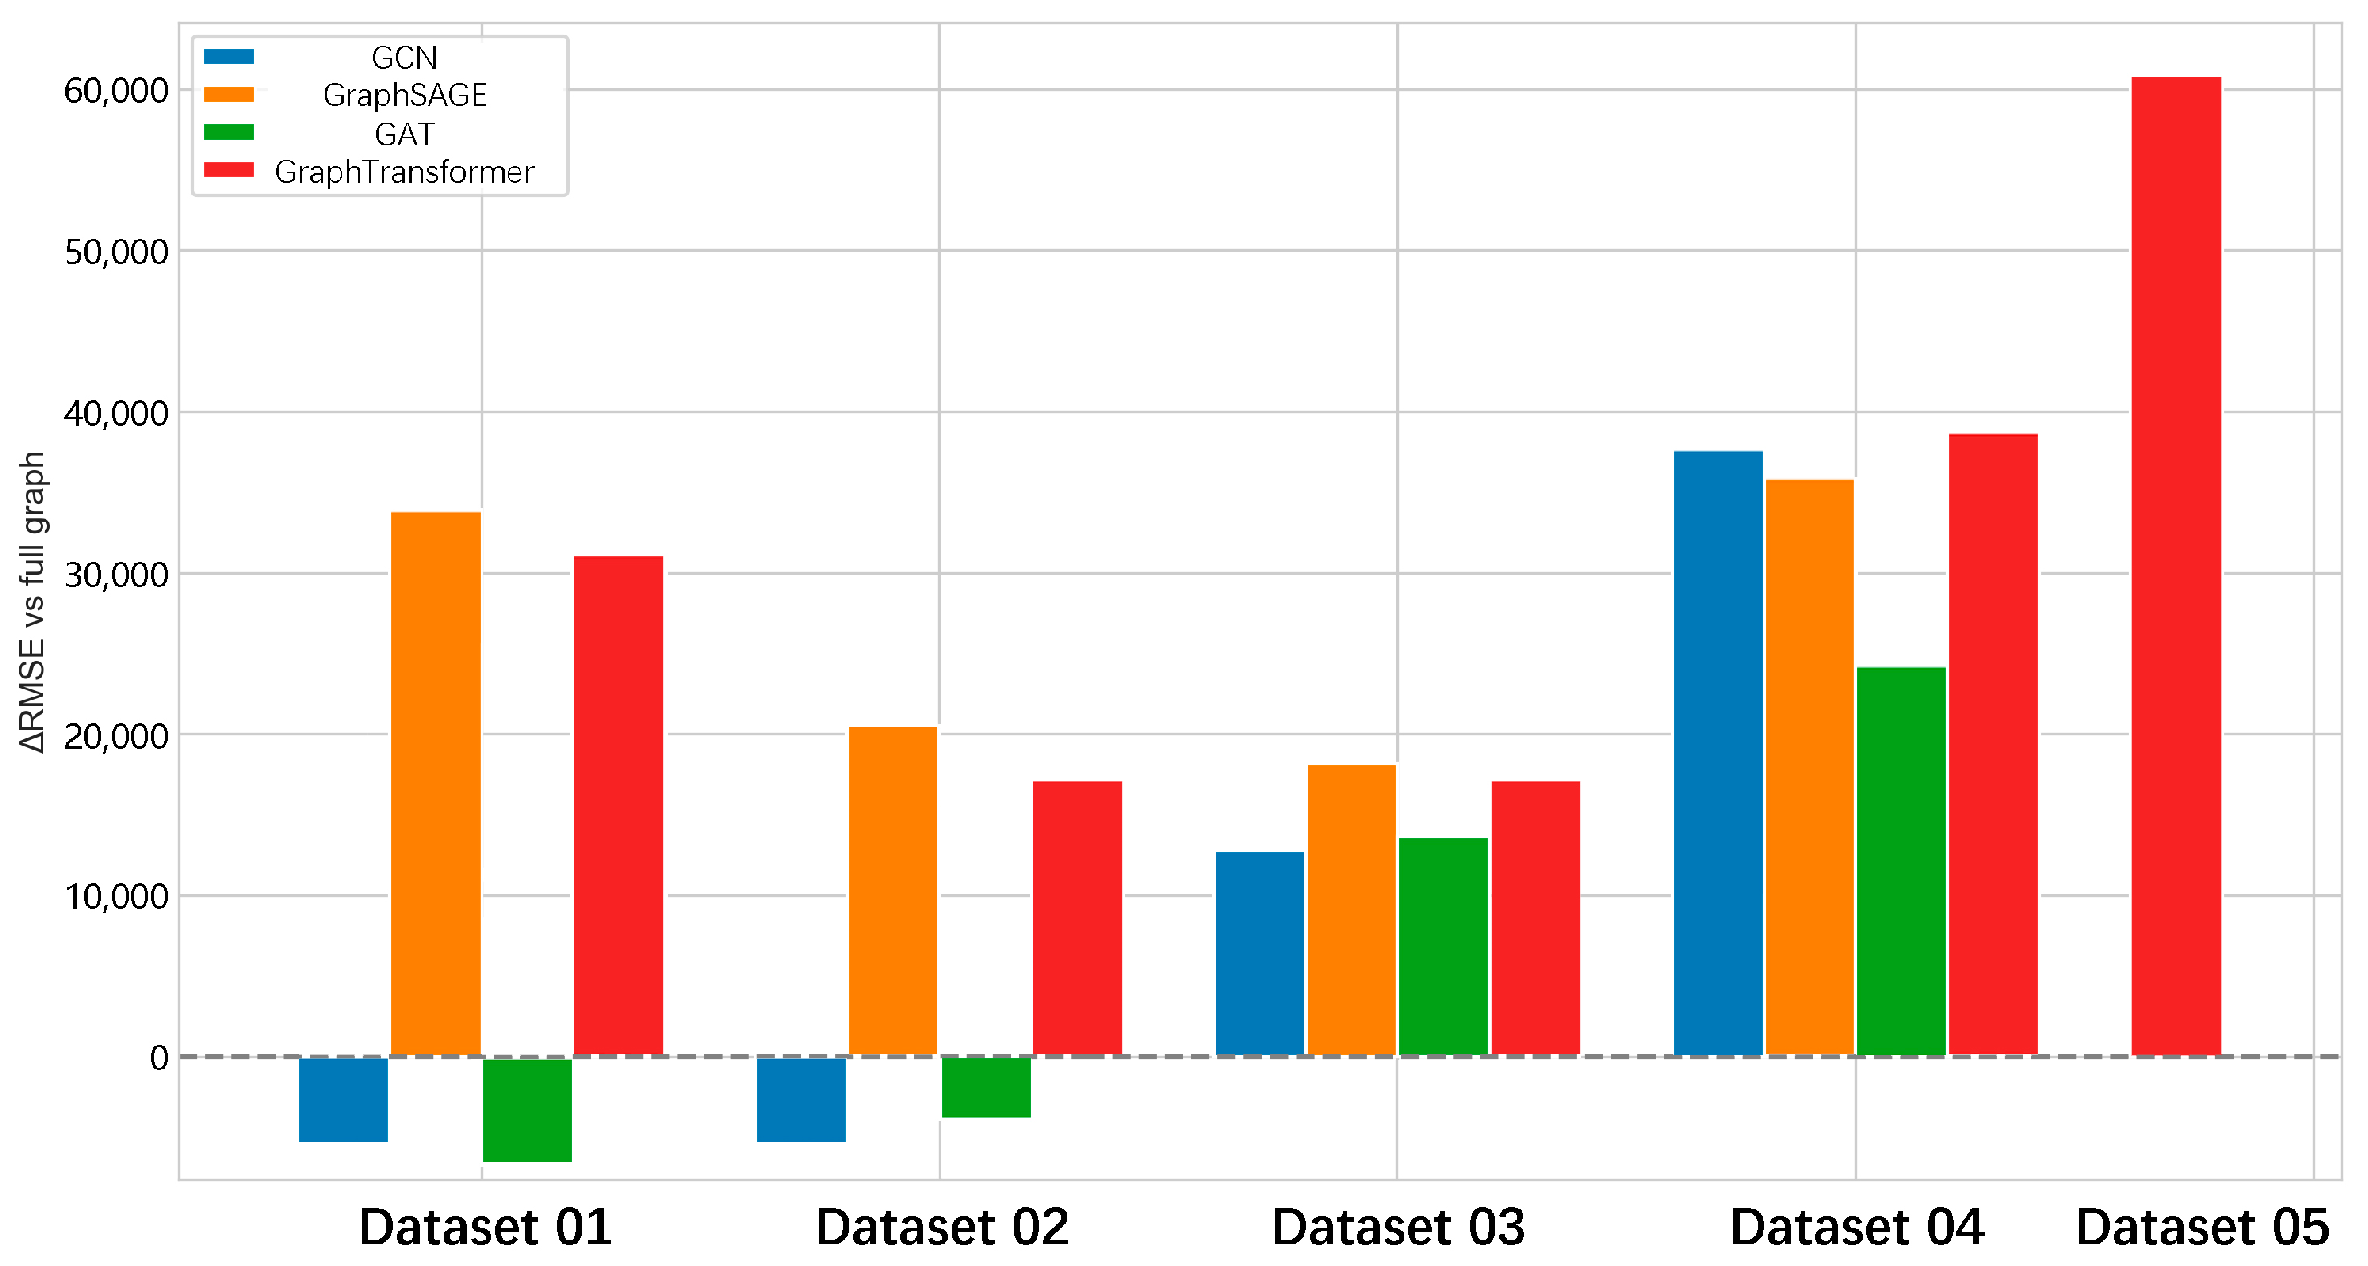
As shown in
Figure 25, in terms of
, the results demonstrate that all GNN models heavily rely on key structural and feature components for intelligent building energy prediction. For graph structures, both GraphSAGE and GraphTransformer exhibit a high dependency on BLG graph, where removing the buildings layout topology (Dataset 01) causes a more severe performance degradation (
) than losing BZG (Dataset 02), while GCN and GAT show negative anomalies that suggest full-graph connections may induce structural noise or over-smoothing in simpler architectures. The result confirmed that the building layout arrangements have a significant impact on
.
Regarding node attributes, (Dataset 04) emerges as the universally dominant predictor whose absence triggers a massive performance collapse across all models, whereas the secondary feature, (Dataset 03), yields a more moderate impact.
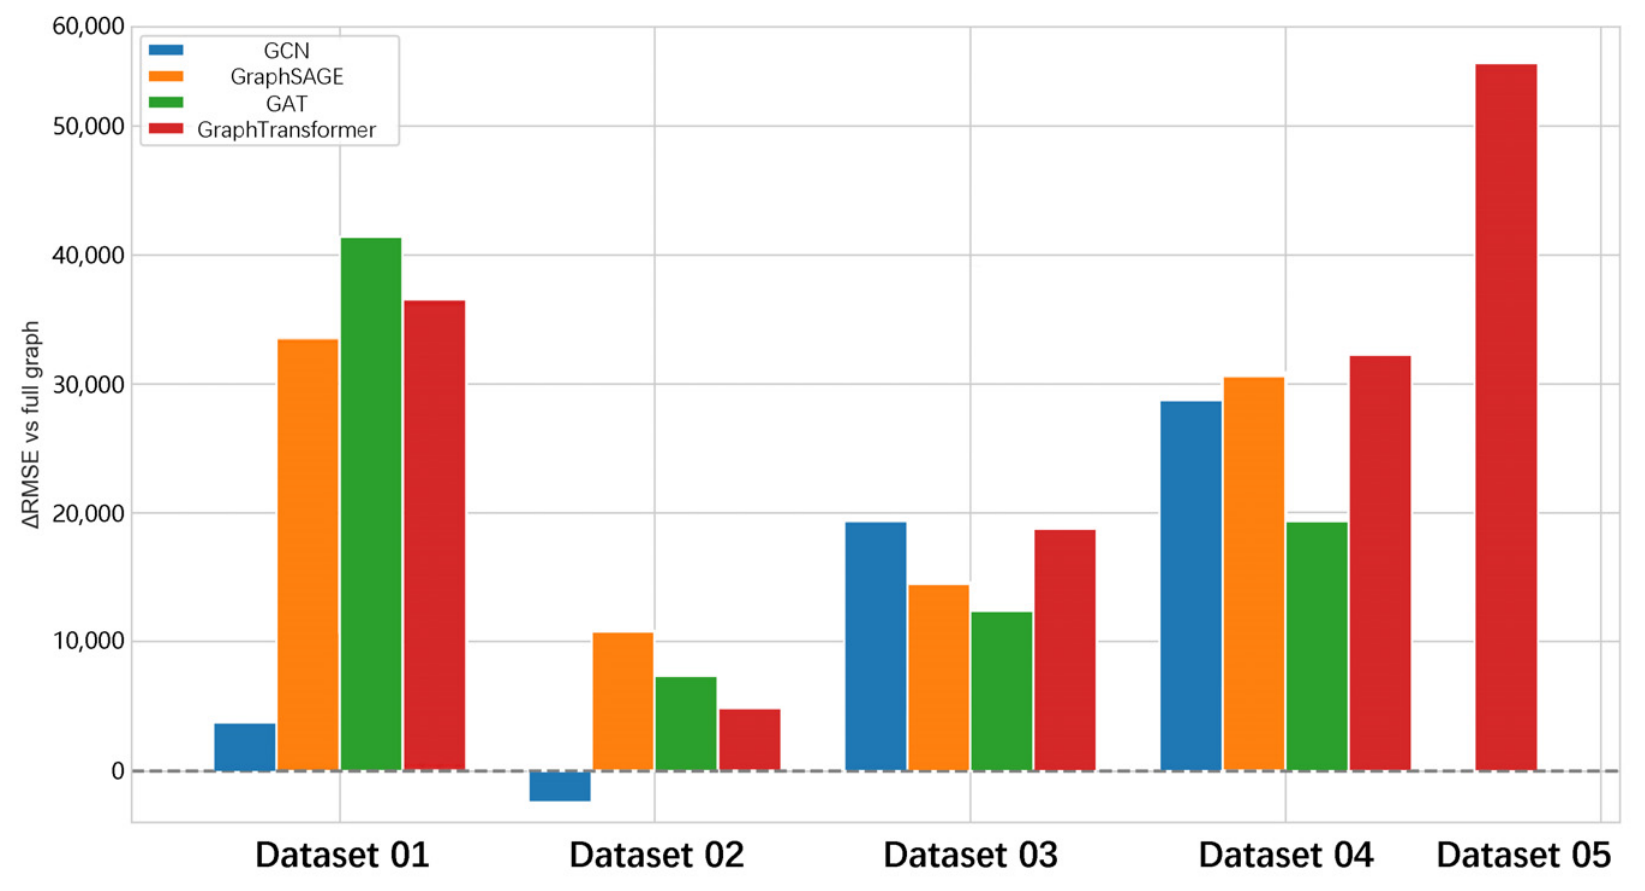
As shown in
Figure 26, in terms of
, the result demonstrates that all GNN models exhibit high sensitivity to specific topological structures, node features. Regarding graphs, removing the BLG topology (Dataset 01) has a significantly higher
than removing the BZG topology (Dataset 02) across nearly all models. This confirms that macro-level spatial arrangements exert a dominant influence on
.
For node attributes, the higher error surge across all models is in Dataset 04, rather than in Dataset 03, thus validating as a more critical predictor than for heating loads.
Finally, as shown in
Figure 19 and
Figure 20, the skip connection (Dataset 05) emerges as an absolute prerequisite for the architectural stability of the GraphTransformer, with its removal causing severe performance collapses in both
(
) and
(
) predictions. This catastrophic degradation across both seasonal scenarios underscores that without skip connections, deep global attention layers inherently suffer from severe over-smoothing and representation washing.
4.5. The Efficiency and Accuracy Validation
As shown in
Table 18, the GNN model achieved a 98.8% reduction in computational time compared to traditional EnergyPlus physics-based simulations. However, establishing such GNN surrogate models needs a large number of calculation results, which also need time during the initial data-generation phase. Consequently, the GNN framework offers a clear operational advantage in massive, multi-scenario block energy assessment tasks. On the other hand, the conventional EnergyPlus simulations still have advantages for low-volume computations.
As shown in
Table 19, compared to recent State-of-the-Art urban energy models, both traditional machine learning and the GNN frameworks have excellent, comparable predictive fidelity, with
values exceeding 0.85. Crucially, the GNN architecture significantly enhances data efficiency, using a dataset size representing a mere 7.3% of that required by Riccardo Taormi et al. [
72] and 11.6% of that used by Ahad Montazeri et al. [
73] This minimized data dependency shows the superior deployment scalability and broader practical prospects of the GNN-based framework.