


Abstract
Translation and post-editing both integrate reading into bilingual text production, yet it remains unclear which computational predictors from multilingual pre-trained models best account for translators’ reading patterns across task types and translation directions. We recruited twenty-six Chinese L1 translators who completed en→zh and zh→en translation and post-editing tasks, yielding 104 eye-tracking sessions. Dependent measures were source reading time (TrtS), target reading time (TrtT), and target production duration (Dur). Predictors were derived from two model architectures, a decoder-only language model (LM) and an encoder–decoder neural machine translation (NMT) model, and they included monolingual surprisal, translation surprisal with source context, and attention features computed from models’ internal weights. Analyses showed that LM surprisal provided the strongest account of target reading, while source reading was most strongly predicted by encoder self-attention with LM surprisal, a robust secondary predictor, and target production duration drew on both LM and NMT translation surprisal. Direction effects were broader than task effects, especially on target measures. These findings suggest that although translation reading is bilingual in task structure, cumulative reading time is best explained by monolingual LM surprisal, whereas production duration additionally reflects NMT translation surprisal and revision behavior.
1. Introduction
Eye movements during reading reveal the cognitive processes that support language comprehension [1,2]. Research has examined word recognition and sentence processing and their interactions during monolingual reading [3]. By contrast, evidence remains limited for bilingual task contexts such as translation and post-editing (PE), in which reading is coupled with cross-language reformulation. Reading for translation appears to differ from within-language reading as it takes more working memory resources and may involve activation of target language lexical entries [4].
Translation is a form of bilingual text production in which comprehension of the source text is closely tied to production of the target text [5]. Translators do not first finish reading and then begin writing; rather, they move back and forth between comprehension, formulation, and monitoring as the target text is incrementally produced [6,7]. Eye movements in translation should therefore reflect not only text understanding, but also the demands of bilingual text production.
Post-editing differs from translation in one key respect. Although both tasks require readers to coordinate source and target text, post-editing additionally involves evaluating, verifying, and selectively revising the draft [8,9]. Therefore, translation and PE should be treated neither as monolingual reading nor as the same form of bilingual reading [10].
Multilingual pre-trained models offer a novel way to quantify reading activity during both tasks. Prior work has modeled human translation (HT) difficulty using surprisal, entropy, and neural predictors derived from corpus or deep neural models [11,12,13]. In this study, we focus on two model families that differ in architecture, decoder-only language models (LMs) and encoder–decoder neural machine translation (NMT) models. LM predictors capture predictability within a language through monolingual surprisal [14,15], whereas NMT predictors capture uncertainty with source context and target predictions [13].
It remains unclear, however, whether these predictors relate to translators’ eye movements across source and target reading and whether such relations vary by task type or translation direction. The present study is guided by three research questions.
- RQ1: Do translators’ reading measures align more strongly with LM surprisal or NMT predictors?
- RQ2: Does the relationship between predictors and reading behavior vary across translation directions?
- RQ3: Do human translation (HT) and post-editing (PE) differ in the relation between predictors and reading behavior?
2. Related Work
2.1. Eye Movements Across Reading Tasks
Eye movements provide evidence of ongoing processing during reading. In monolingual reading, measures such as first-fixation duration, gaze duration, and regressions have been used to characterize lexical access, sentence integration, and oculomotor control [16]. Early measures are often interpreted as more sensitive to relatively early stages of word processing, whereas later measures such as total reading time and regressions are more informative about later integration difficulty, monitoring, and rereading [17].
Eye movement patterns, however, are not always consistent across reading situations. Task demands can alter both temporal and spatial aspects of reading behavior. For example, proofreading and reading for comprehension lead to different fixation and saccade patterns [18]. At the page level, thorough reading, skimming, and spell-checking also produce different patterns [19].
In bilingual reading, L2 differs from L1 reading, with L2 involving longer fixation durations and more frequent regressions [20]. Lexical processing in bilingual reading can be influenced by cross-language activation even in strongly unilingual sentence contexts [21]. Moreover, evidence on parafoveal processing in bilingual readers suggests that cross-language semantic information is not accessible during reading in a monolingual language mode, consistent with the partial selectivity hypothesis of bilingual language control [22]. These findings highlight that bilingual reading behavior depends not only on general L1 or L2 proficiency differences but also on task-level language mode.
2.2. Translation and Post-Editing as Bilingual Reading
Bilingual comprehension and production are closely coordinated during translation [6,7]. Rather than executing sequential steps, translators simultaneously consult the source text and plan target output [5]. Recent work suggests that non-literality, lexical or morphological restructuring, and compound handling can redistribute effort across source reading, target reading, and production duration [10,23]. Eye-tracking and key-logging studies further show that L1→L2 translation places greater demands on target text production while L2→L1 translation draws more heavily on source text comprehension [24], and that preparatory reading patterns vary by both translation mode and direction [25].
2.3. Surprisal, Reading Time, and Model Fit
Rooted in information theory, surprisal quantifies how unexpected a token is given its preceding context. It has been proposed as a measure of processing difficulty [14,15]. Higher surprisal is often associated with slower reading [26,27,28,29]. In practice, it has been estimated using n-gram models [30], probabilistic grammars [14], and more recently large language models (LLMs) [28,31]. The mapping from model quality to predictive power is, however, non-trivial, since perplexity does not always produce good fits to human processing [31,32]. Training experiments show that Transformer-based LM surprisal aligns best with human reading times after about two billion training tokens; past a certain threshold, however, additional training data cause surprisal estimates to diverge from expectations, inverting the scaling relationship between model size and its fit to human reading [33]. Recent evidence further indicates that model fit improves when models better match readers’ experience and task ecology [34], and that text difficulty can modulate predictability effects beyond what average surprisal accounts for [35].
Recent work has also explored whether LLMs can serve as cognitively plausible models of human language processing. A central finding is that larger models do not necessarily produce better predictions of human reading behavior; rather, internal representations from intermediate layers often align better with human measures than final-layer predictions do [36]. This layer-wise correspondence suggests that different processing stages in neural LMs may map onto different aspects of human cognition, with early layers approximating incremental parsing and later layers capturing more integrated comprehension [37].
Beyond reading times, LLMs have been shown to predict neural correlates of language processing. Studies using EEG have demonstrated that LLM internal representations, particularly from middle layers, correlate with N400 potentials [36]. Similarly, research on spontaneous speech production suggests that fine-tuned LLMs can capture production variables such as speech reduction and prosodic prominence that reflect cognitive processing load [38].
The cognitive plausibility of LLMs also depends on the training mechanism and dataset. Models trained on spoken language corpora show stronger alignment with human production measures than those trained exclusively on written text [38], underscoring the role of ecological validity; recent work demonstrates that LLMs fine-tuned on sentence-level psycholinguistic norms can predict human reading times better than baseline predictors, though zero-shot performance remains inconsistent [39].
2.4. Multilingual Pre-Trained Models in Translation Difficulty Modeling
Model architecture has been shown to affect the predictive power of surprisal for human reading behavior, independent of perplexity [31,32]. Decoder-only and left-to-right LMs provide monolingual next-token predictability. By contrast, multilingual encoder–decoder NMT models estimate target probabilities conditioned on source context and therefore offer translation surprisal [13,40]. Prior studies show that NMT surprisal and derived features can explain variation in human translation difficulty [12,13]. Attention and entropy descriptors may add complementary information beyond surprisal [41,42], but attention weights should be interpreted as internal variables of the model rather than direct measurements of human attention [41,43].
2.5. Research Gap and Positioning of the Present Study
Several questions remain unresolved. First, while surprisal theory has been extensively tested in monolingual reading, it remains unclear whether monolingual LM surprisal or bilingual NMT translation surprisal better captures processing difficulty during translation, where comprehension and production are interleaved across languages. Second, the ongoing debate about whether LM surprisal effects reflect genuine contextual prediction or frequency confounds [44] has not been extended to bilingual task settings, where NMT predictions offer a qualitatively different predictability measure. Third, prior translation difficulty modeling has focused on human translation alone [13], leaving open whether post-editing, which adds evaluation and revision to the production process, changes the mapping between predictability and behavioral measures or merely reduces mean effort. The present study attempts to address these gaps by jointly modeling source reading, target reading, and target production duration in a within-subject design.
3. Materials and Methods
3.1. Participants, Materials, and Apparatus
We designed a within-subject experiment comparing task type (translation vs. post-editing) and direction (en→zh vs. zh→en). Drafts for post-editing were generated with gpt-4o-2024-05-13 [45], and 26 Chinese L1 student translators (Mage = 22.96, SD = 1.40) were recruited from a university in central China. Eye movements were recorded with an EyeLink 1000 Plus in remote mode at 1000 Hz, with 13-point calibration performed before each task. The display was configured at 1280 × 1024 pixels and 75 Hz refresh rate. User activity data were synchronized via Translog-II [46].
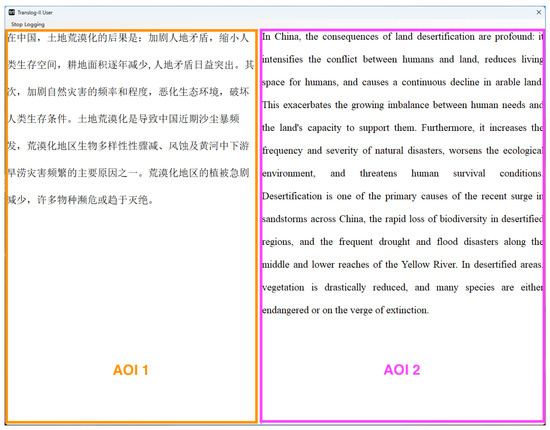
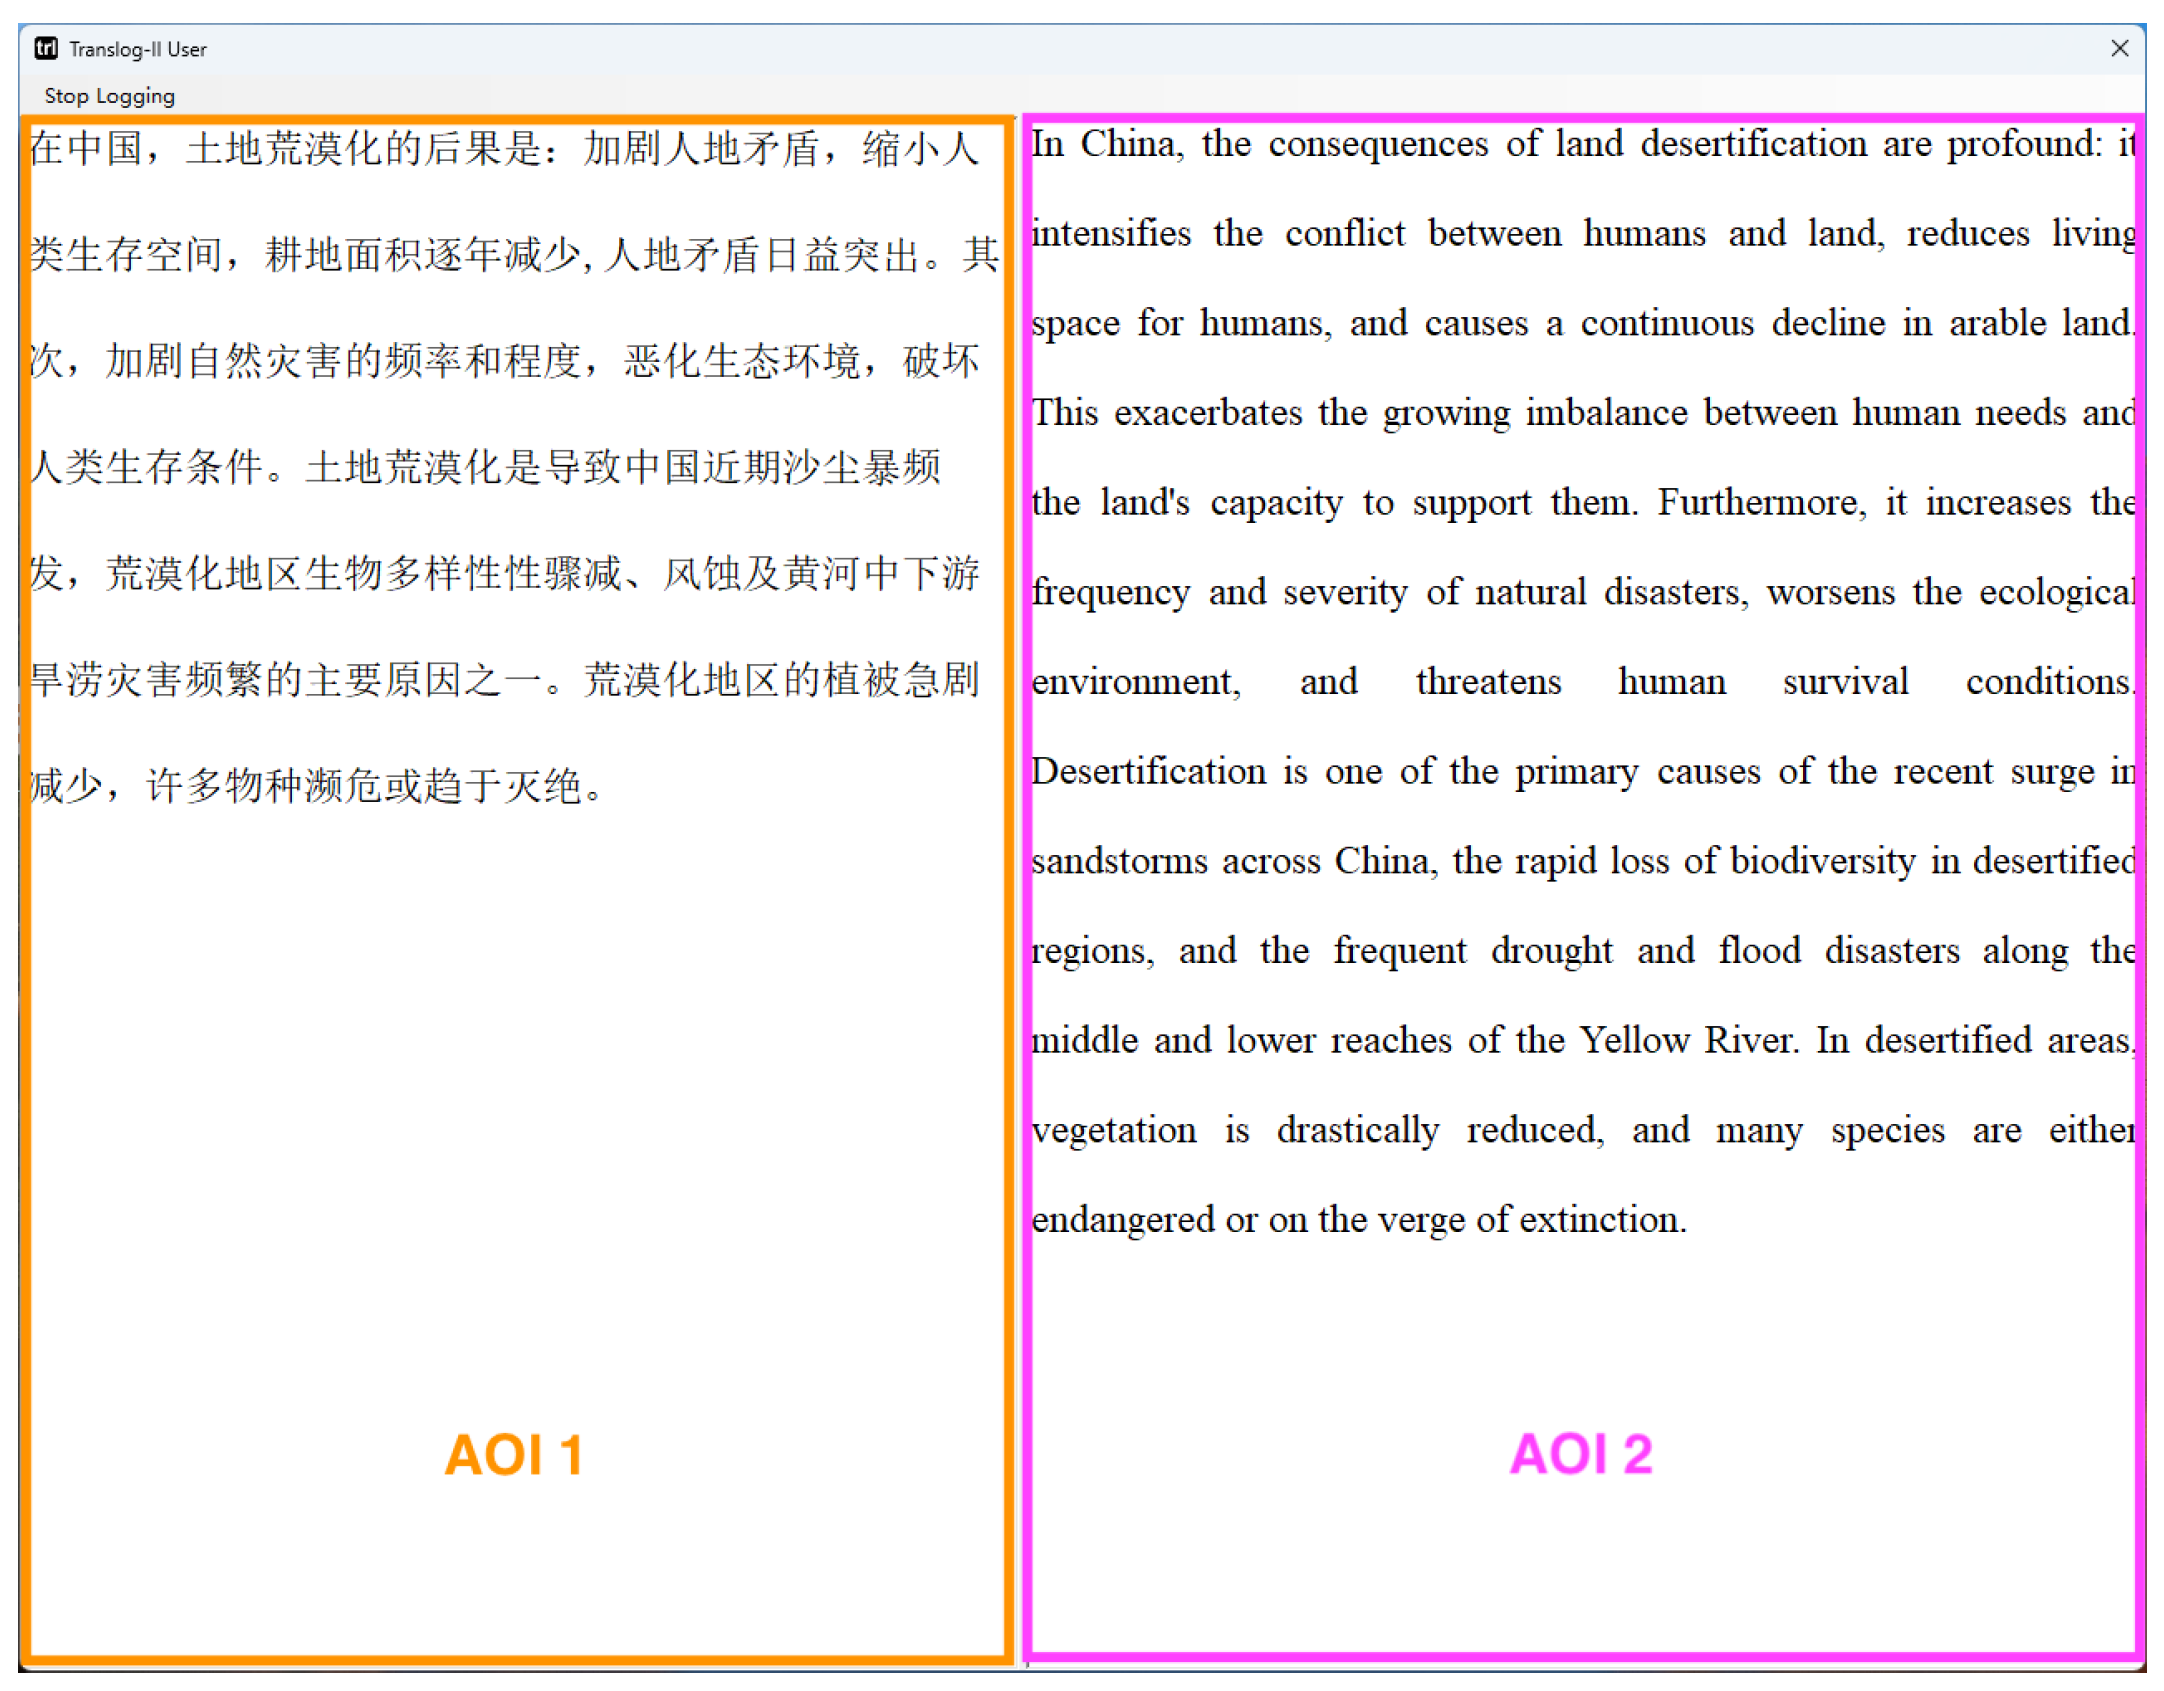
We used a horizontal split-screen layout with source text positioned left and target text right. Chinese text used SimSun font and English text used Times New Roman, both at 18-point size with double line spacing. Figure 1 illustrates the screen layout and the two defined Areas of Interest (AOIs).
Figure 1.
Screen layout in Translog-II showing the two AOIs. AOI 1 covers the source text region; AOI 2 covers the target text region. Eye-tracking measures were extracted from two AOIs.
Task materials comprised four non-literary texts drawn from English–Chinese translation examinations [47]. They are suitable for practical translation testing [48]. Each task was kept to approximately 85 words, with Chinese word counts computed after tokenization. The order of passages was randomly assigned to participants.
To match the difficulty of source materials, the readability of each task material was assessed by mdeberta-v3-base-readability, a fine-tuned model capable of estimating readability scores across languages [49]. Scores estimated by the model were closely clustered across texts, ranging from 19.06 to 19.86, with condition means of 19.38 for translation and 19.54 for post-editing materials. As an additional check, three professional translators (mean experience: 5.3 years) independently rated each text on a 10-point difficulty scale (1 = very easy, 10 = extremely difficult). As shown in Table 1, human ratings broadly aligned with the automated scores, suggesting that the difficulty of the materials was comparable.
Table 1.
Expert difficulty ratings (1–10 scale) for the four source passages.
3.2. Data Filtering and Alignment
Gaze data were aligned so that fixations could be mapped onto source and target units. At the token level, each unit corresponds to one aligned source or target token; at the segment level, aligned tokens are merged into one unit. In the aligned tables, TrtS and TrtT capture reading behavior, while Dur was treated as a production measure.
We applied separate filtering criteria to each measure. For TrtS and TrtT, values below 20 ms were excluded, following previous work [13,50]. Because post-editing sessions may contain zero values in target duration for unedited units, Dur was modeled only when it was positive and at least 20 ms. All retained continuous values were log transformed before modeling.
Under these filters, source TrtS covered 89.8% of token-level observations and 90.9% of segment-level observations; target TrtT covered 90.4% of token-level observations and 92.2% of segment-level observations; positive target Dur covered 52.6% of target tokens and 53.9% of target segments. Two post-editing sessions (zh→en) were excluded from token- and segment-level analyses because heavy structural editing during post-editing broke the source–target token alignment; these sessions contributed only sentence-level observations. The full experimental dataset comprises 104 task sessions.
3.3. Model Selection and Feature Extraction
We selected two pre-trained models to compute the predictors of processing difficulty. mGPT [51], a multilingual causal language model, generates left-to-right surprisal estimates for each language independently, computed as token-level negative log-probabilities over sentence sequences. NLLB-200 [40], a multilingual NMT model, provides probabilities with source context alongside encoder, decoder, and cross-attention tensors. Masked language models such as BERT [52] were not considered, as they rely on bidirectional context and do not natively produce left-to-right sequence probabilities. The resulting estimates are pseudo-likelihoods [53,54], and therefore do not yield surprisal values equivalent to those of causal language models.
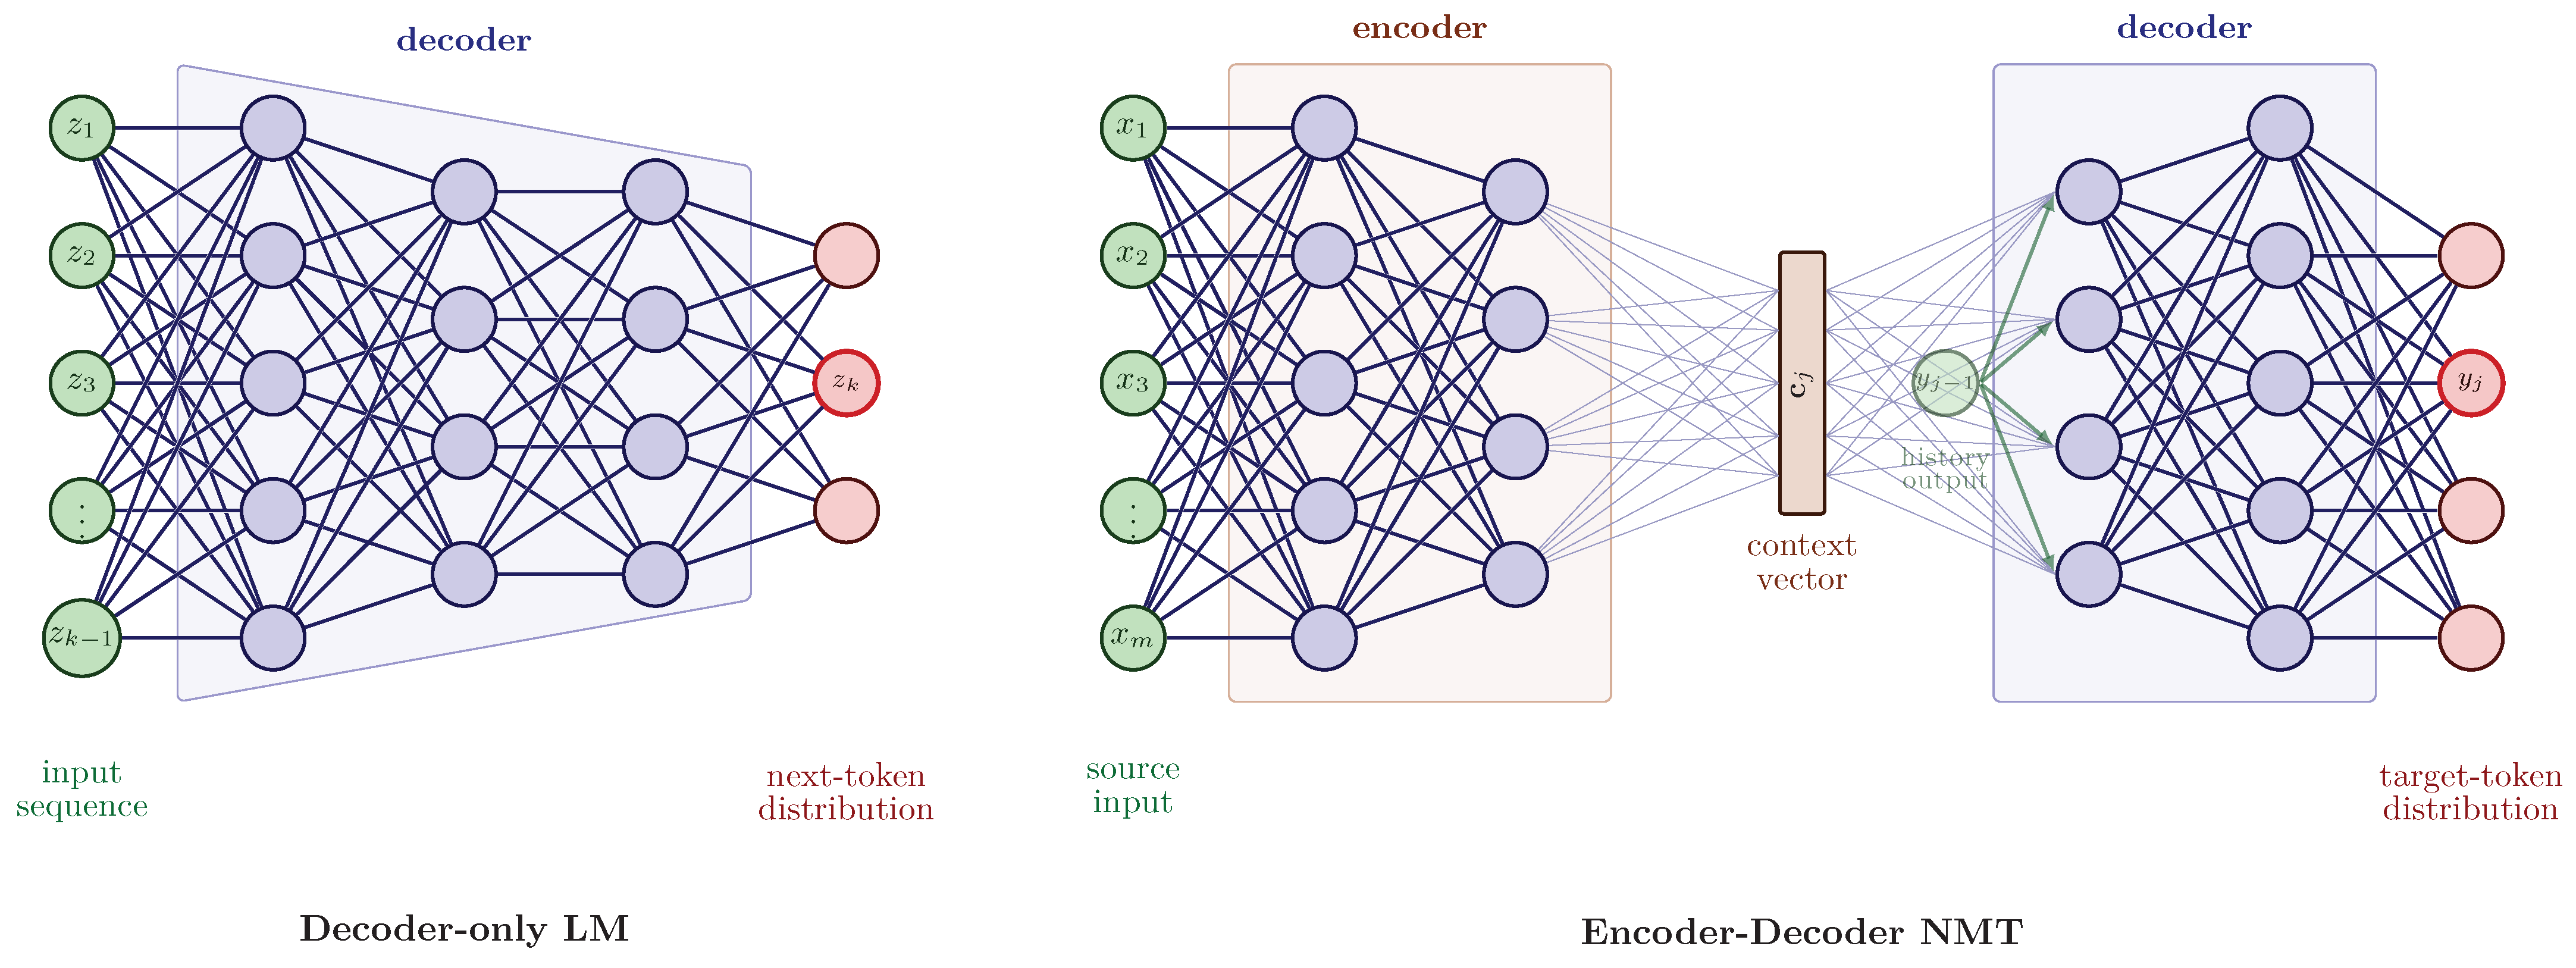
As illustrated in Figure 2, two processing difficulty predictors can be derived from these two architectures. The first is monolingual surprisal, the negative log probability of a token given its preceding context, provided by decoder-only LMs. The second is translation surprisal, which quantifies the uncertainty in target generation conditioned on both the source sequence and preceding target context, derived from the encoder–decoder NMT model [13].
Figure 2.
Architecture comparison of the two model types used in this study. (Left): A decoder-only LM maps input sequence to a next-token distribution. (Right): An encoder–decoder NMT model encodes and combines that source representation with the previous target tokens to predict .
Formally, let be a source sequence and a target sequence. Monolingual surprisal on the source side is
and for monolingual surprisal in the target text
For the encoder–decoder NMT model, translation surprisal is
where u and v are source and target token sets, respectively. At the token level, u and v are singletons. At the segment level, u and v denote merged aligned units, and segment-level surprisal is the sum of the token-wise surprisals inside that aligned unit. Attention features, originally computed per token, are averaged across tokens within the same aligned unit before segment-level modeling. Models of source reading use , while models of target reading include both and . The modeling framework is summarized in Figure 3.
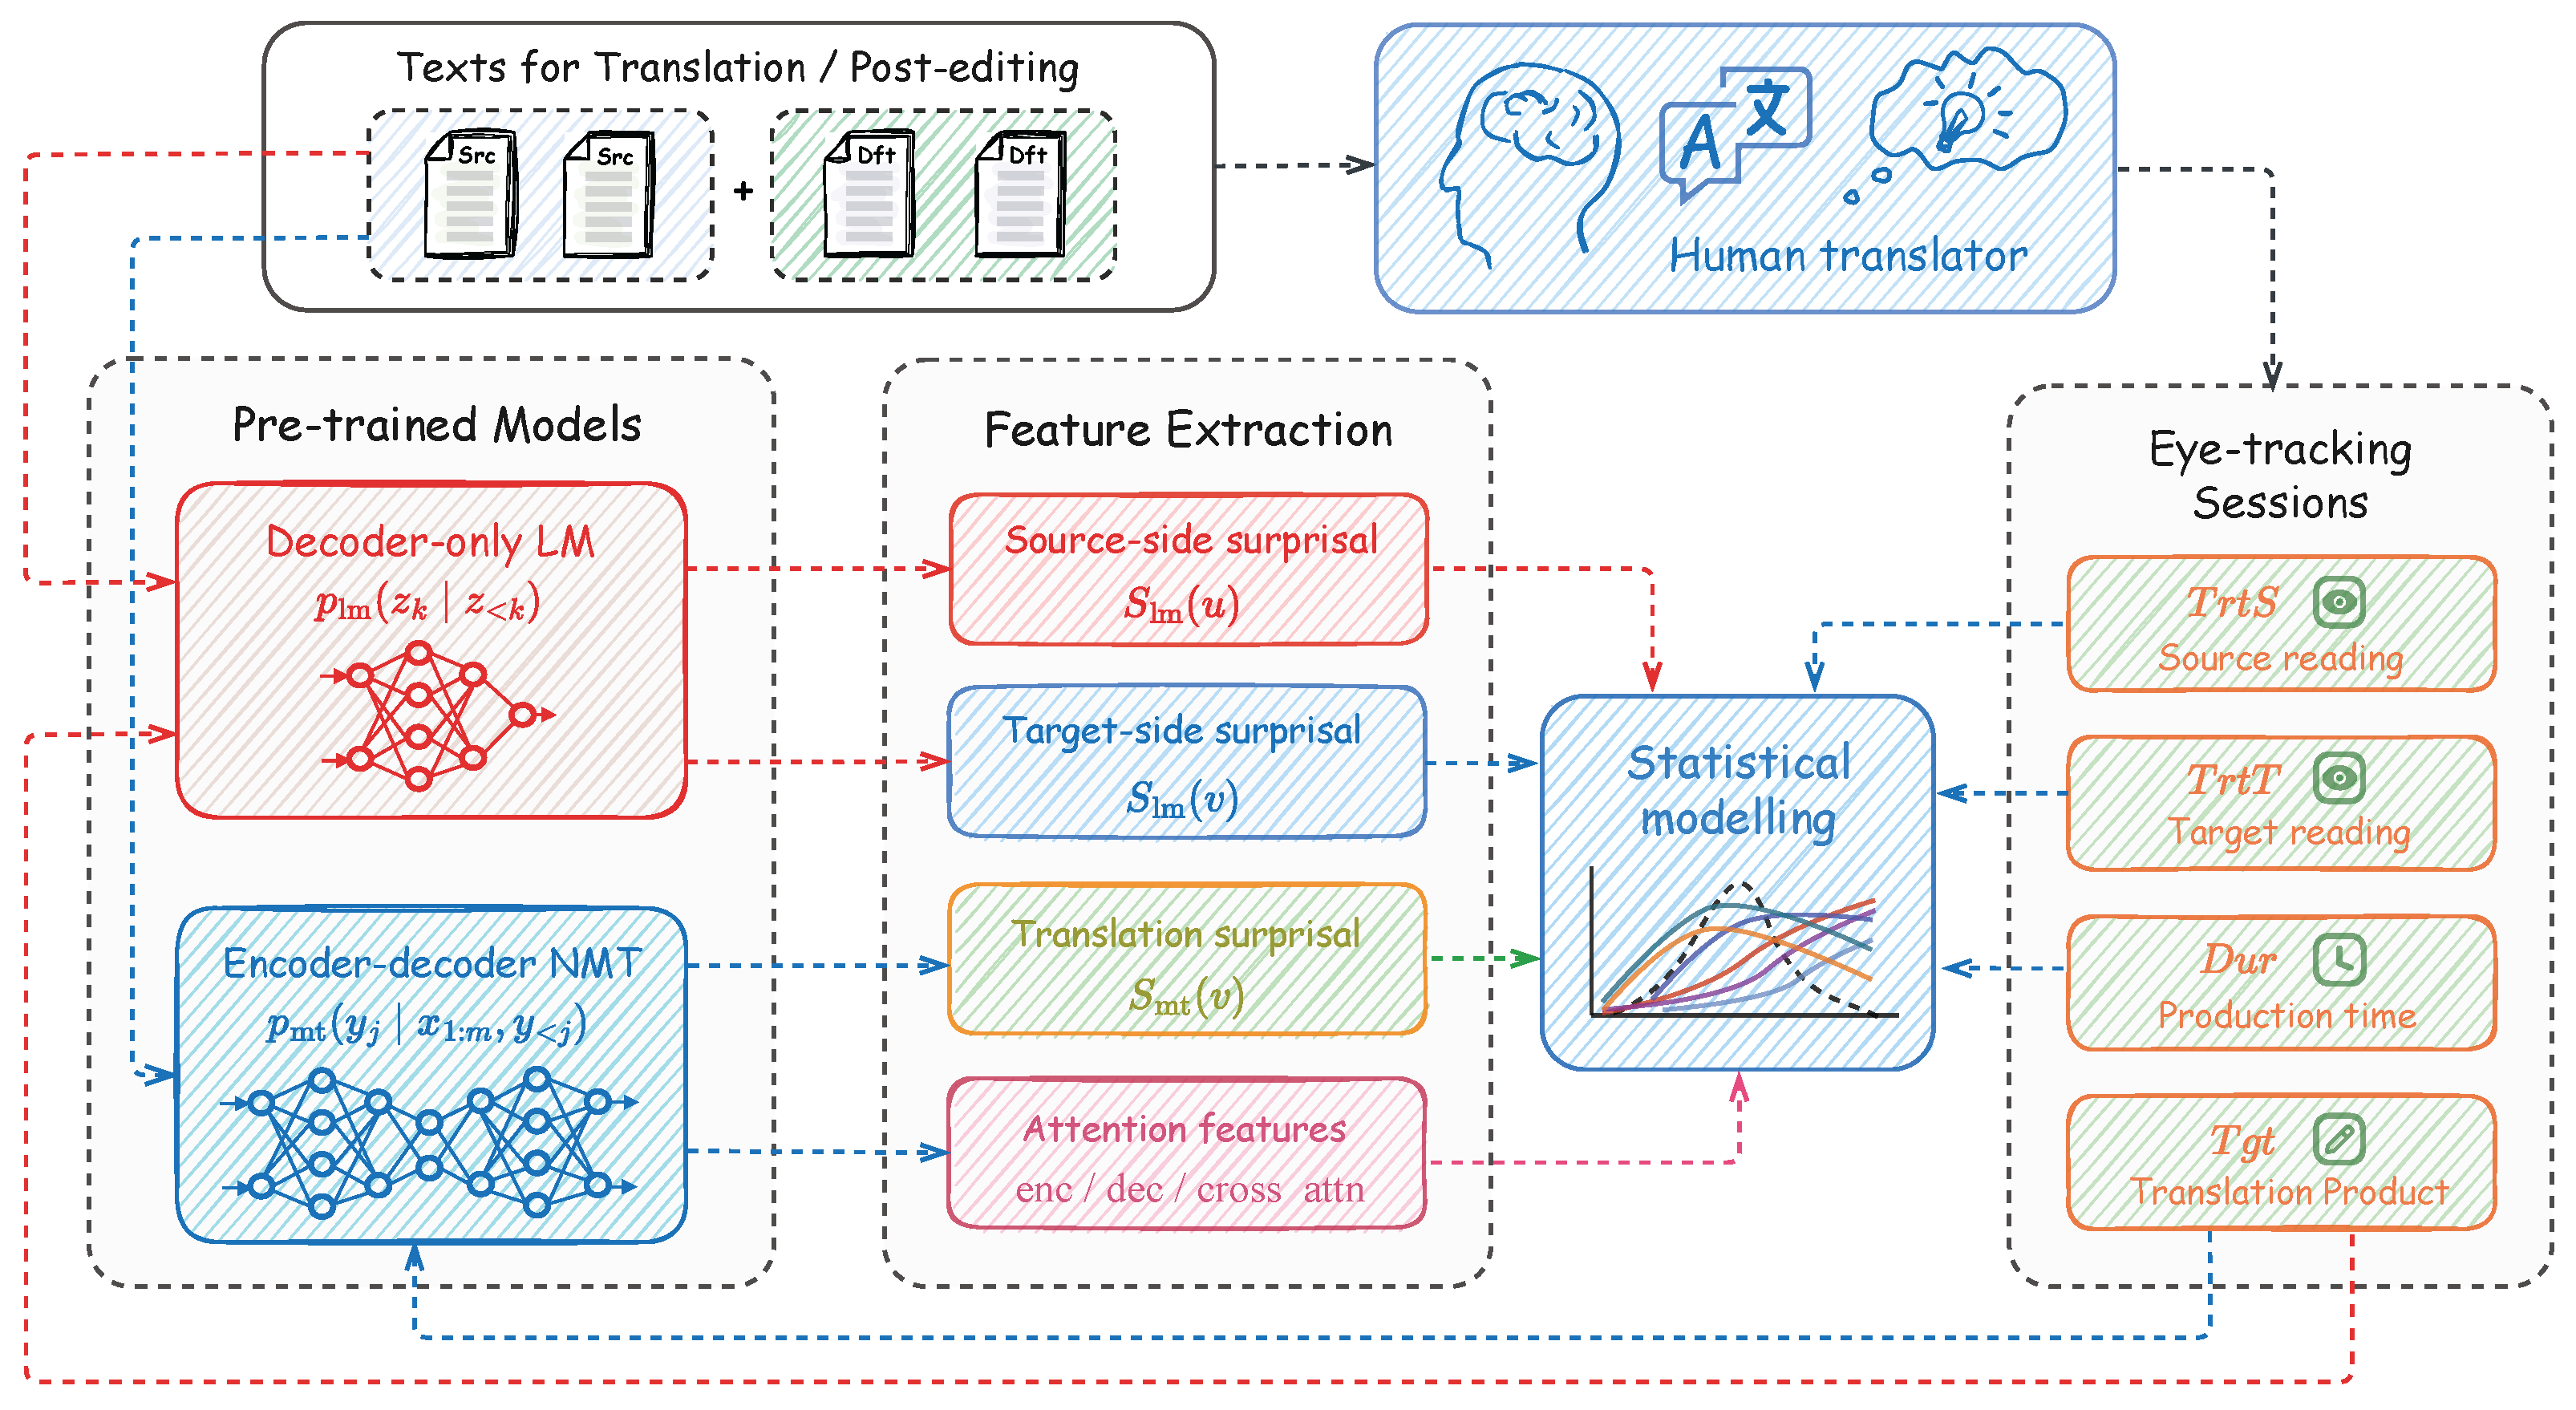
Figure 3.
Overview of the modeling framework. Model-derived predictors and attention features are compared with measures from eye-tracking sessions.
For other attention feature extraction, we followed prior work [13] and stacked attention tensors across all layers and heads from the encoder self-attention, cross-attention, and decoder self-attention, and computed two types of scalar features per aligned unit. Coverage features (f) measure the summed attention mass from one set of positions to another, for example, encoder self-attention from a source token to its surrounding context () or cross-attention to the sequence boundary (). Entropy features (H) capture the diffuseness of the attention distribution, with higher values indicating more evenly spread attention. Coverage and entropy features were normalized by the corresponding uniform-attention baseline before being averaged across layers and heads. A complete feature glossary is provided in Appendix A, Table A1, Table A2, Table A3 and Table A4.
3.4. Model Estimation and Statistical Inference
For each combination of side, aggregation level, and outcome, we fitted regression models that account for the structure of the data. The continuous reading outcomes were modeled with linear mixed-effects models (LMMs). The fixed-effect structure compared a control model with an augmented model containing one computational predictor:
Here, length, frequency, and position are segment length, mean unigram frequency, and within-sentence position quantile of the modeled unit. Models of source reading use source-side controls, whereas target reading and duration models use target-side controls. Intercept-only models can yield anticonservative inferences in repeated-measures designs, so we used the maximal random-effects structure [55]. For each comparison, we first fitted the correlated maximal structure justified by the design, with crossed by-participant and by-item random intercepts and correlated by-participant and by-item random slopes for the focal predictor, . When this model failed to converge or returned a singular fit, we applied a stepwise recovery strategy: we first removed the random-effect correlations, then dropped the by-item slope, and finally fell back to random intercepts only, retaining the most complex structure that fit cleanly. Random slopes were specified for the focal predictor; by-item slopes for task type or translation direction were not included because sentence items were nested within task and direction and such slopes are therefore not estimable. When even the random-intercept model produced a boundary fit, it was retained only where the boundary reflected a near-zero random-effect variance rather than a failure of fixed-effect estimation; these cases are flagged in the convergence diagnostics (Appendix B) and interpreted cautiously. For every comparison, the augmented model was matched to a control model with the same random-effects structure, so the likelihood-ratio test evaluated only the added fixed-effect of the focal predictor (). Across the 666 main-effect and residual attention comparisons, 256 used the correlated maximal structure, 85 the uncorrelated maximal structure, 78 the by-participant-slope structure, and 247 the random-intercept structure; no fit was discarded.
Continuous values were log transformed and standardized prior to fitting. Model improvement was quantified by comparing maximum-likelihood fits for the augmented and control models:
A positive indicates that the predictor improves model fit beyond the matched control baseline. We report normalized by the number of observations for comparability across outcome conditions. Because is not comparable across predictors fitted under different random-effects structures, we rank predictors within each outcome by their standardized fixed-effect coefficient , each estimated under the maximal structure where it converged and under the reduced structure otherwise, and use only to test whether a given predictor improves fit over its matched baseline. For inference, raw p-values were obtained from likelihood-ratio tests (, ) comparing the augmented and control models. These p-values were then adjusted with the Benjamini–Hochberg false discovery rate (FDR) procedure [56] and reported as q. Results with are treated as significant. The Benjamini–Hochberg procedure was applied within three families: the 666 main-effect and residual attention comparisons, the 84 interaction comparisons, and the 252 two-part duration comparisons (edit occurrence and conditional duration). All models were fitted in R [57] with the lme4 package [58].
Post-editing duration required an additional model because zeros in Dur are meaningful as they indicate that an aligned unit did not trigger editing or typing. We therefore treated Dur as a two-part process, following the two-part model framework for semicontinuous outcomes [59]. In the first part, a logistic generalized linear mixed model (GLMM) was fitted for edit occurrence, if and 0 otherwise:
Second, for units that were actually edited, we fitted the positive duration LMM described above. Both parts of the two-part model used the same maximal-then-reduced random-effects specification as the reading models, with by-participant and by-item random slopes for the focal predictor reduced on nonconvergence or singularity.
To test whether predictor–behavior relations varied across task types or translation directions, we fitted pooled additive and interaction mixed models. The additive model included the control terms, the predictor, task type, and language direction; the interaction model additionally included either or . The additive and interaction models shared the same random-effects structure—a by-participant random slope for the focal predictor with a by-item intercept, initially fitted as correlated, then reduced to uncorrelated, and finally to random intercepts only on nonconvergence or singularity. By-item slopes for the focal predictor were not added here because the interaction models with that structure rarely converged, and by-item slopes for task type or direction are not estimable given the nesting of items within task and direction. The interaction contrast was defined as:
4. Results
4.1. Predictors of Reading Time and Production Duration
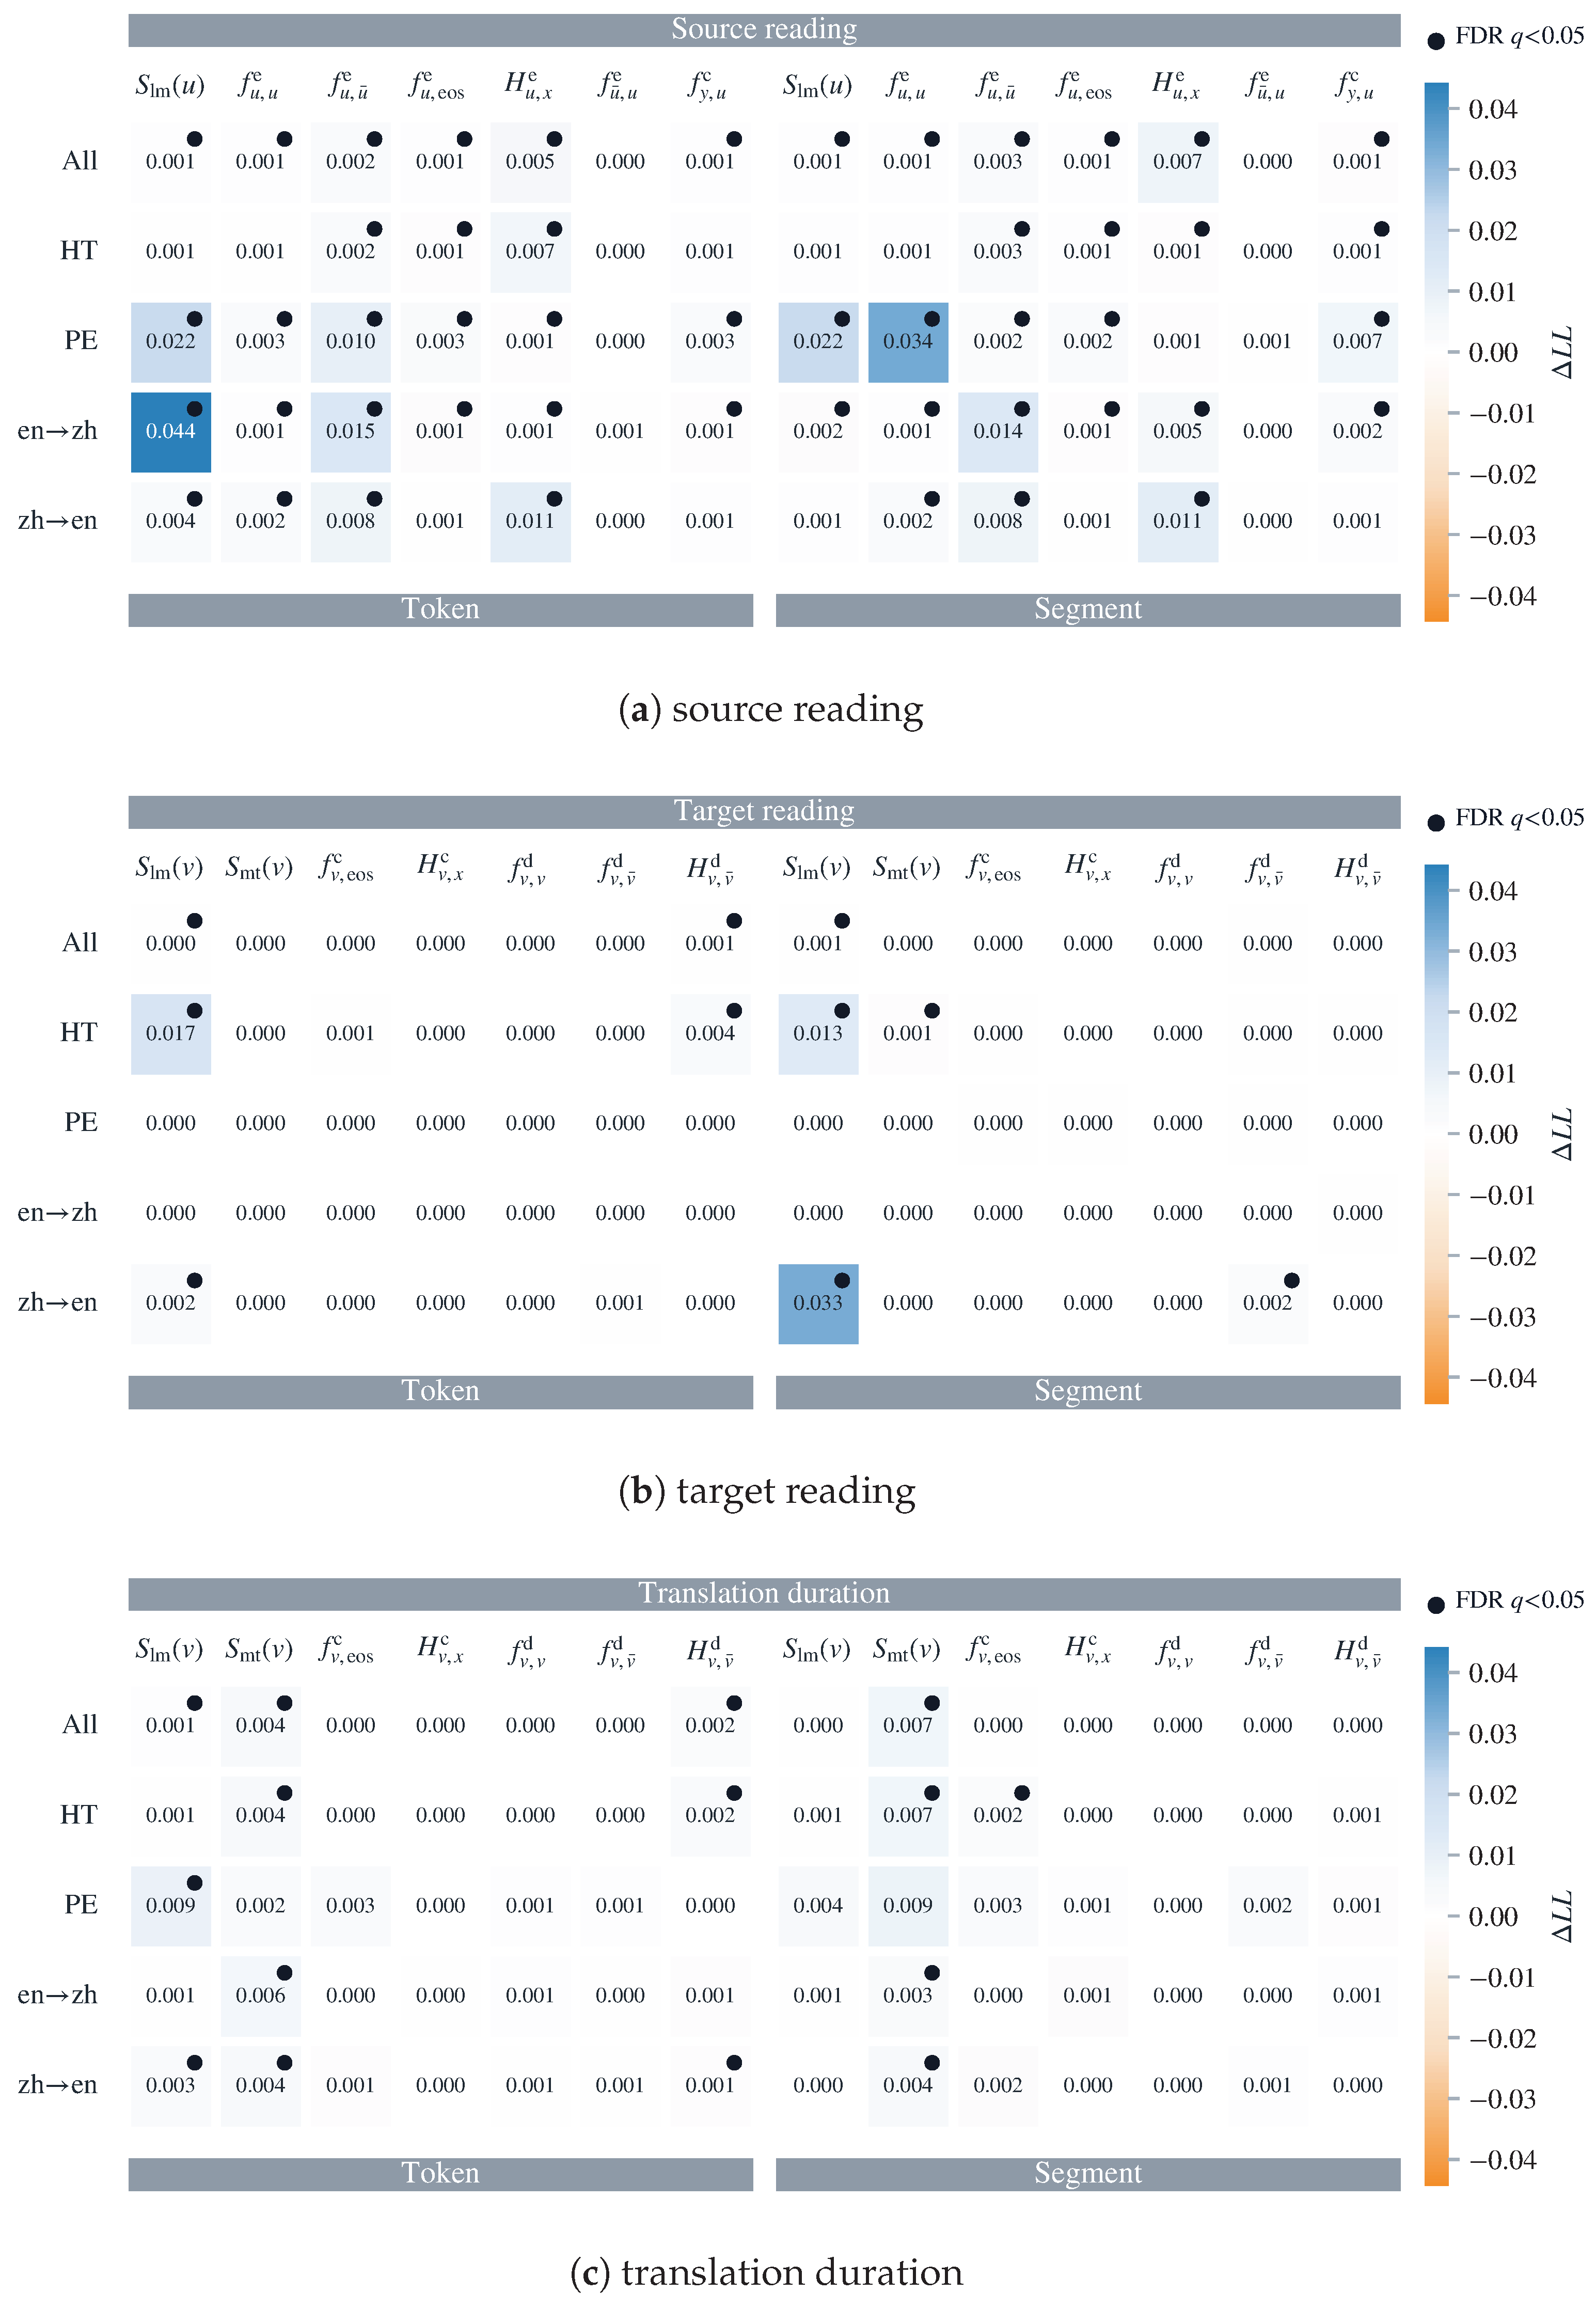
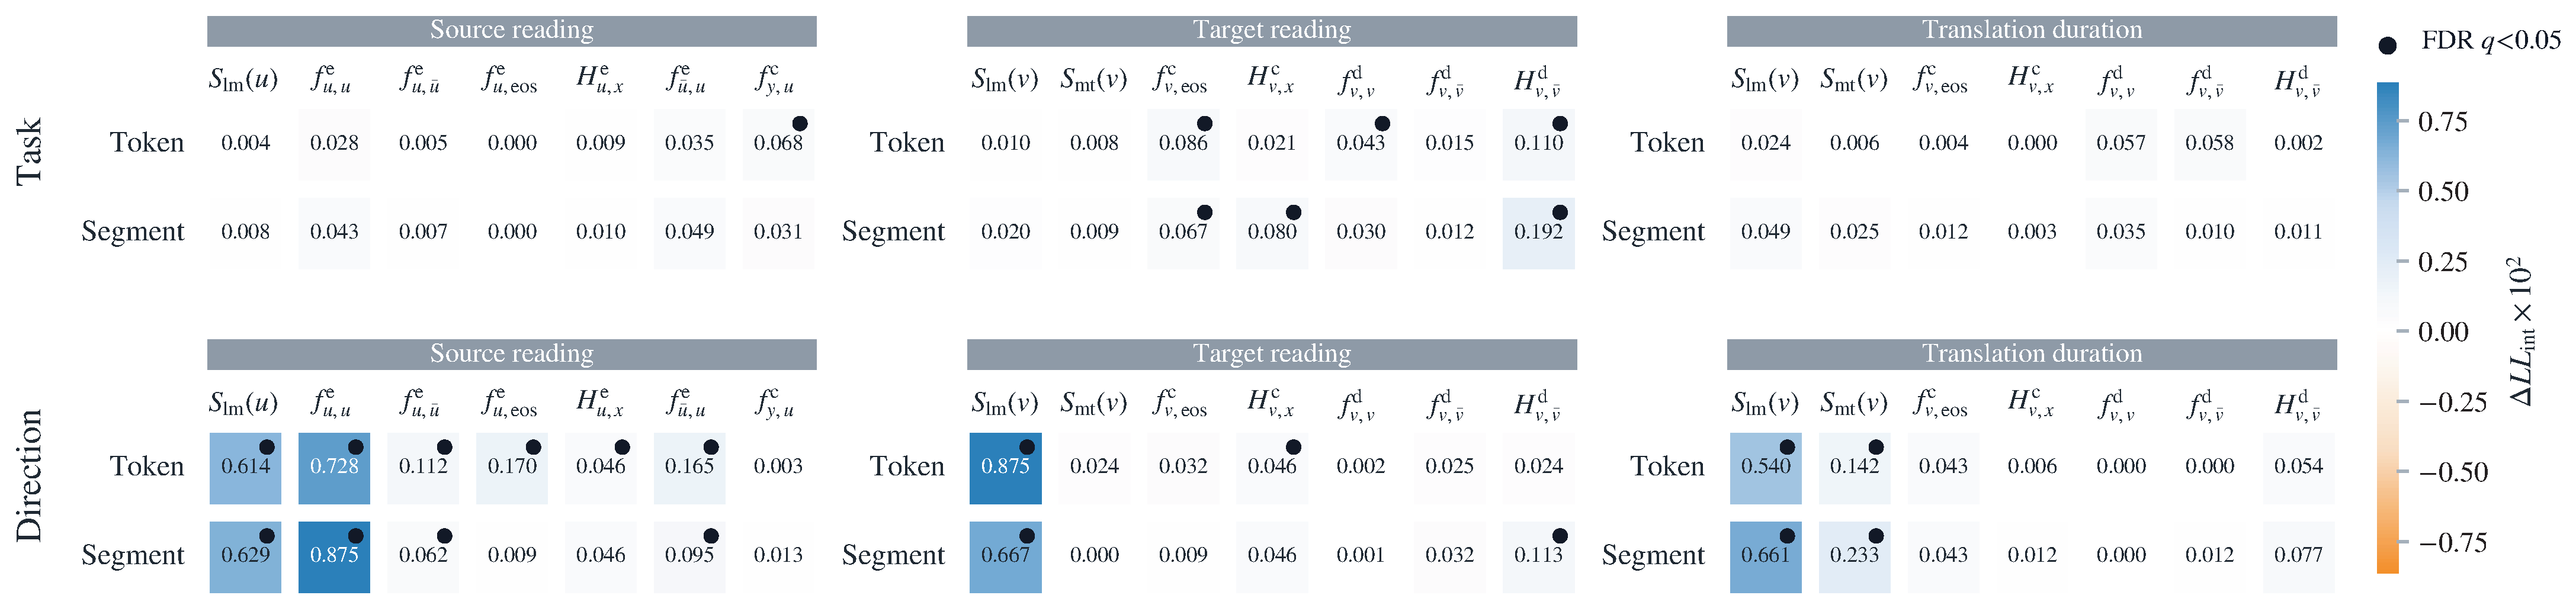
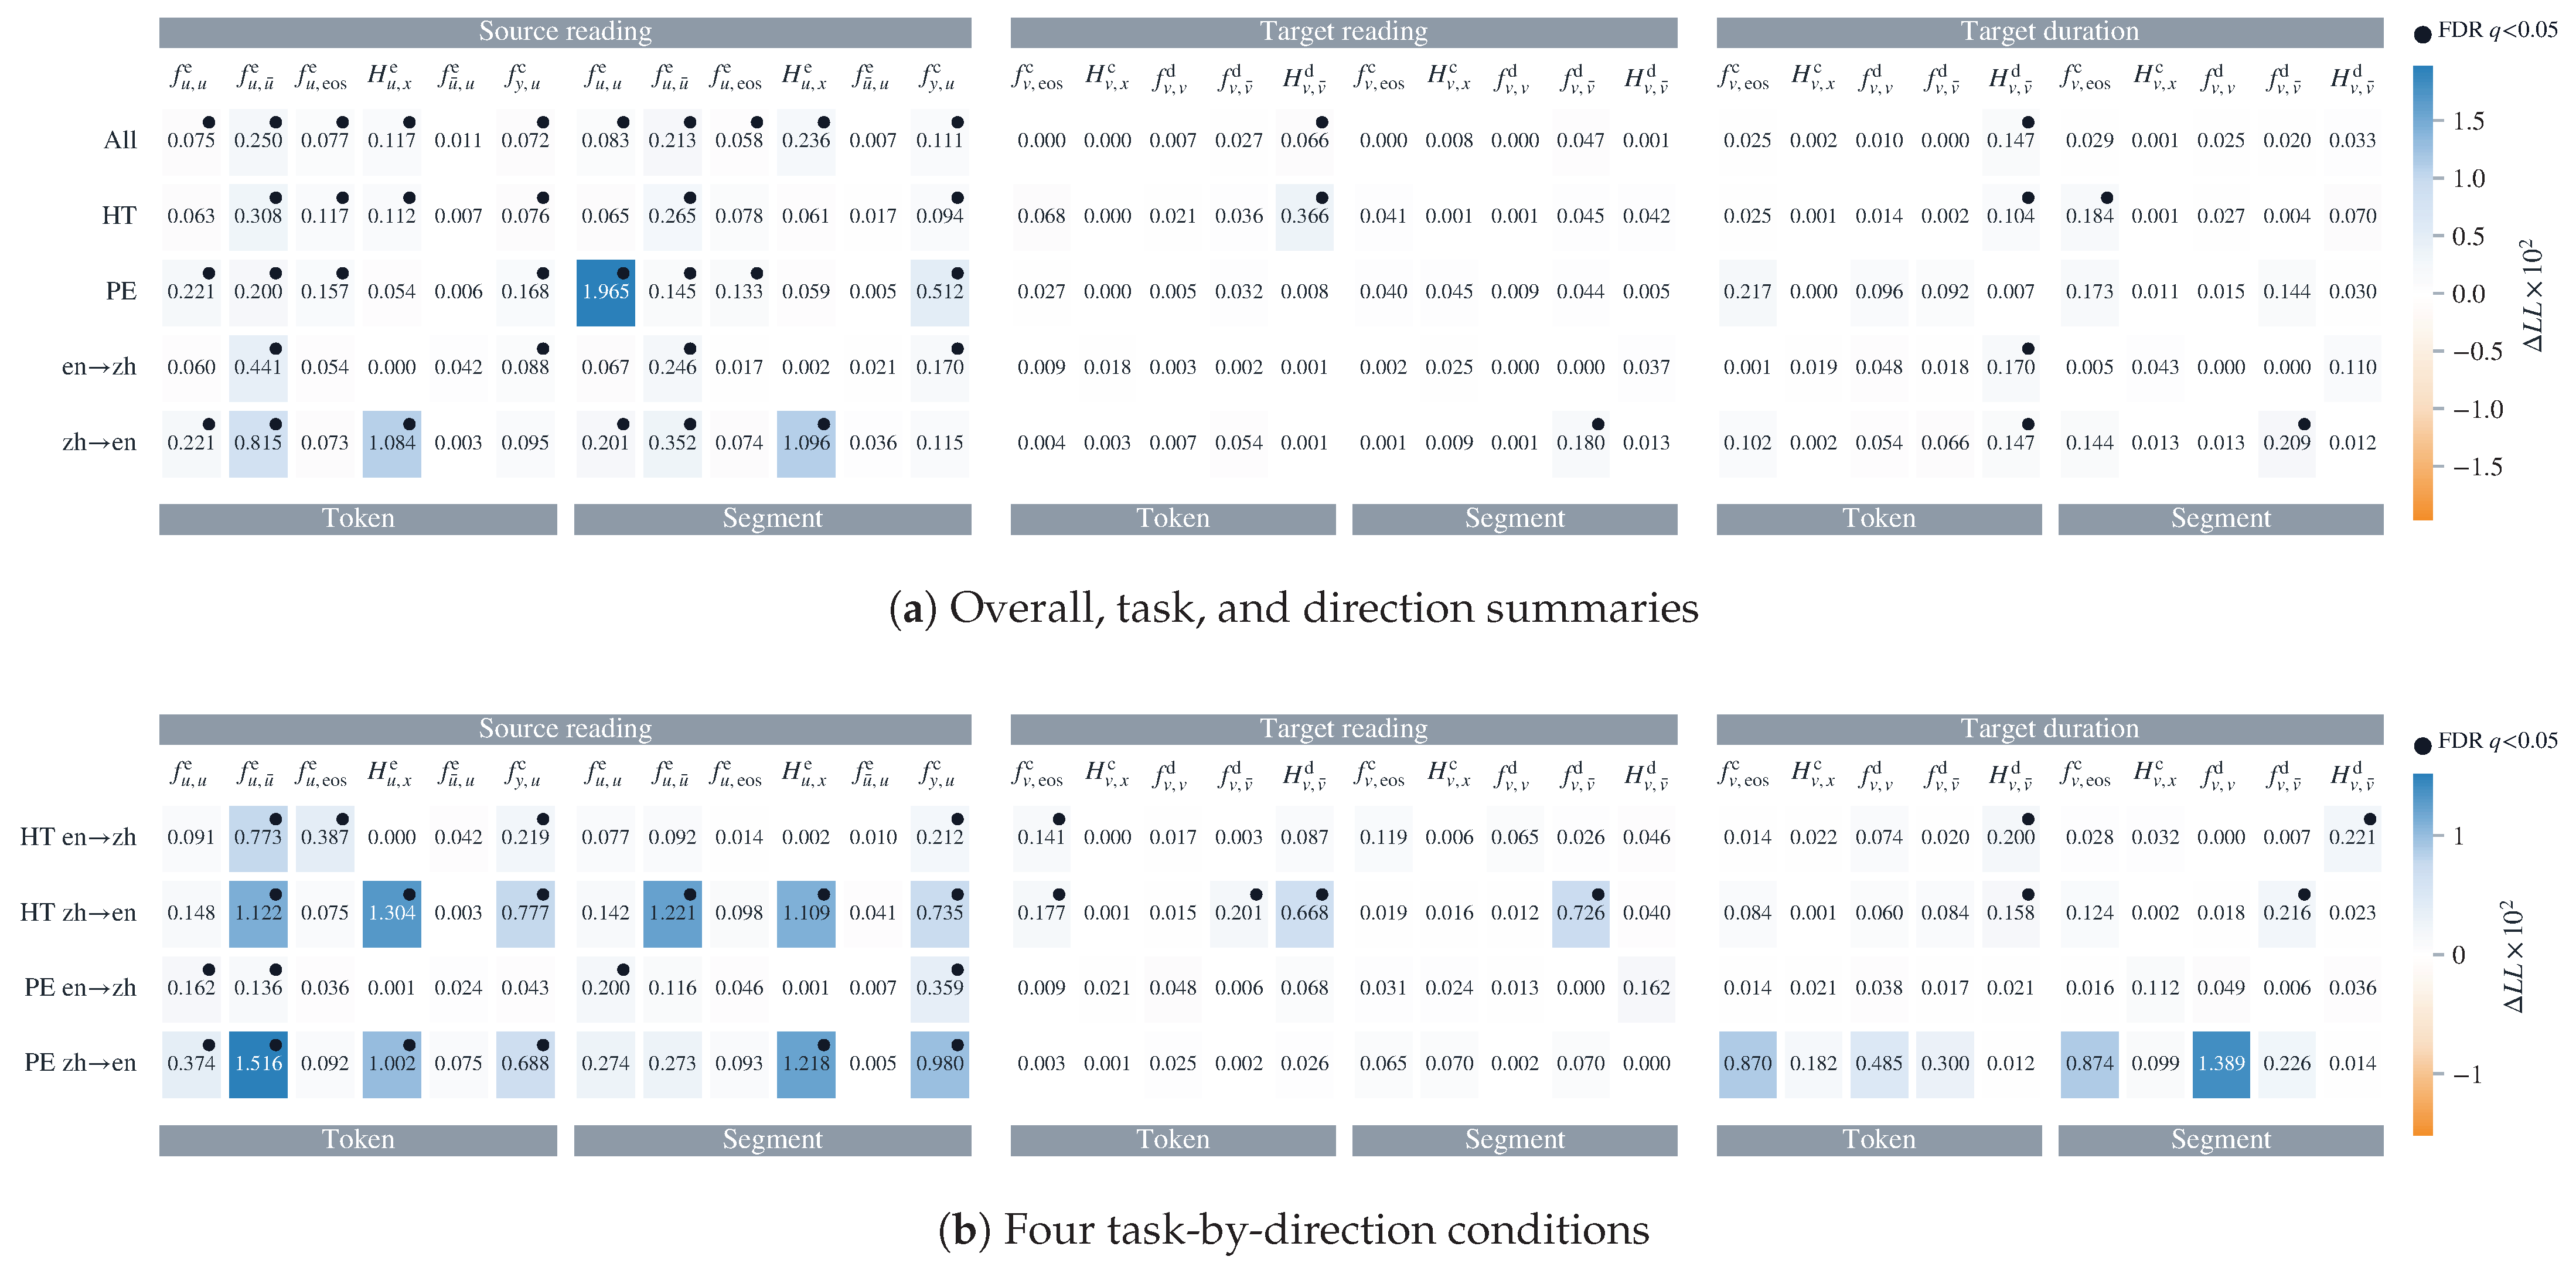
Source reading is most strongly associated with encoder-side attention, together with source text predictability. At both token and segment levels, the encoder self-attention feature carries the largest standardized coefficient, while source LM surprisal remains a robust positive predictor that significantly improves fit. For target reading, target LM surprisal is the strongest predictor at both levels; NMT translation surprisal does not reach significance. For positive Dur, is strongest at the token level, whereas at the segment level, NMT translation surprisal is the strongest significant predictor and is comparable in magnitude () but does not survive FDR correction (Table 2). Predictors are ranked by their standardized coefficient , each estimated under the maximal structure where it converged and under the reduced structure otherwise; and q index indicate whether that predictor improves fit over its matched baseline. Figure 4 extends this comparison with a breakdown by task type and translation direction.
Table 2.
Leading predictor for each outcome and aggregation level, ranked by the standardized fixed-effect coefficient (95% CI) among predictors that significantly improve fit. is the per-observation log-likelihood gain over the matched baseline; p is the likelihood-ratio p-value, and q is the FDR-adjusted value.
Figure 4.
relative to matched control baselines for source reading, target reading, and target duration. Rows summarize the full dataset, task subsets, and direction subsets.
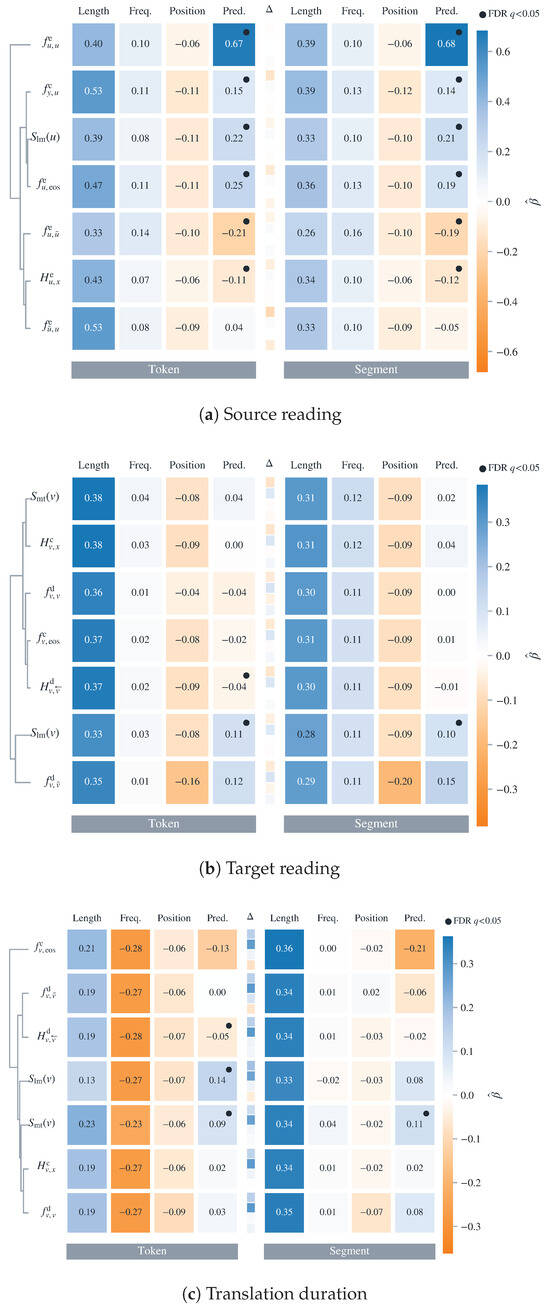
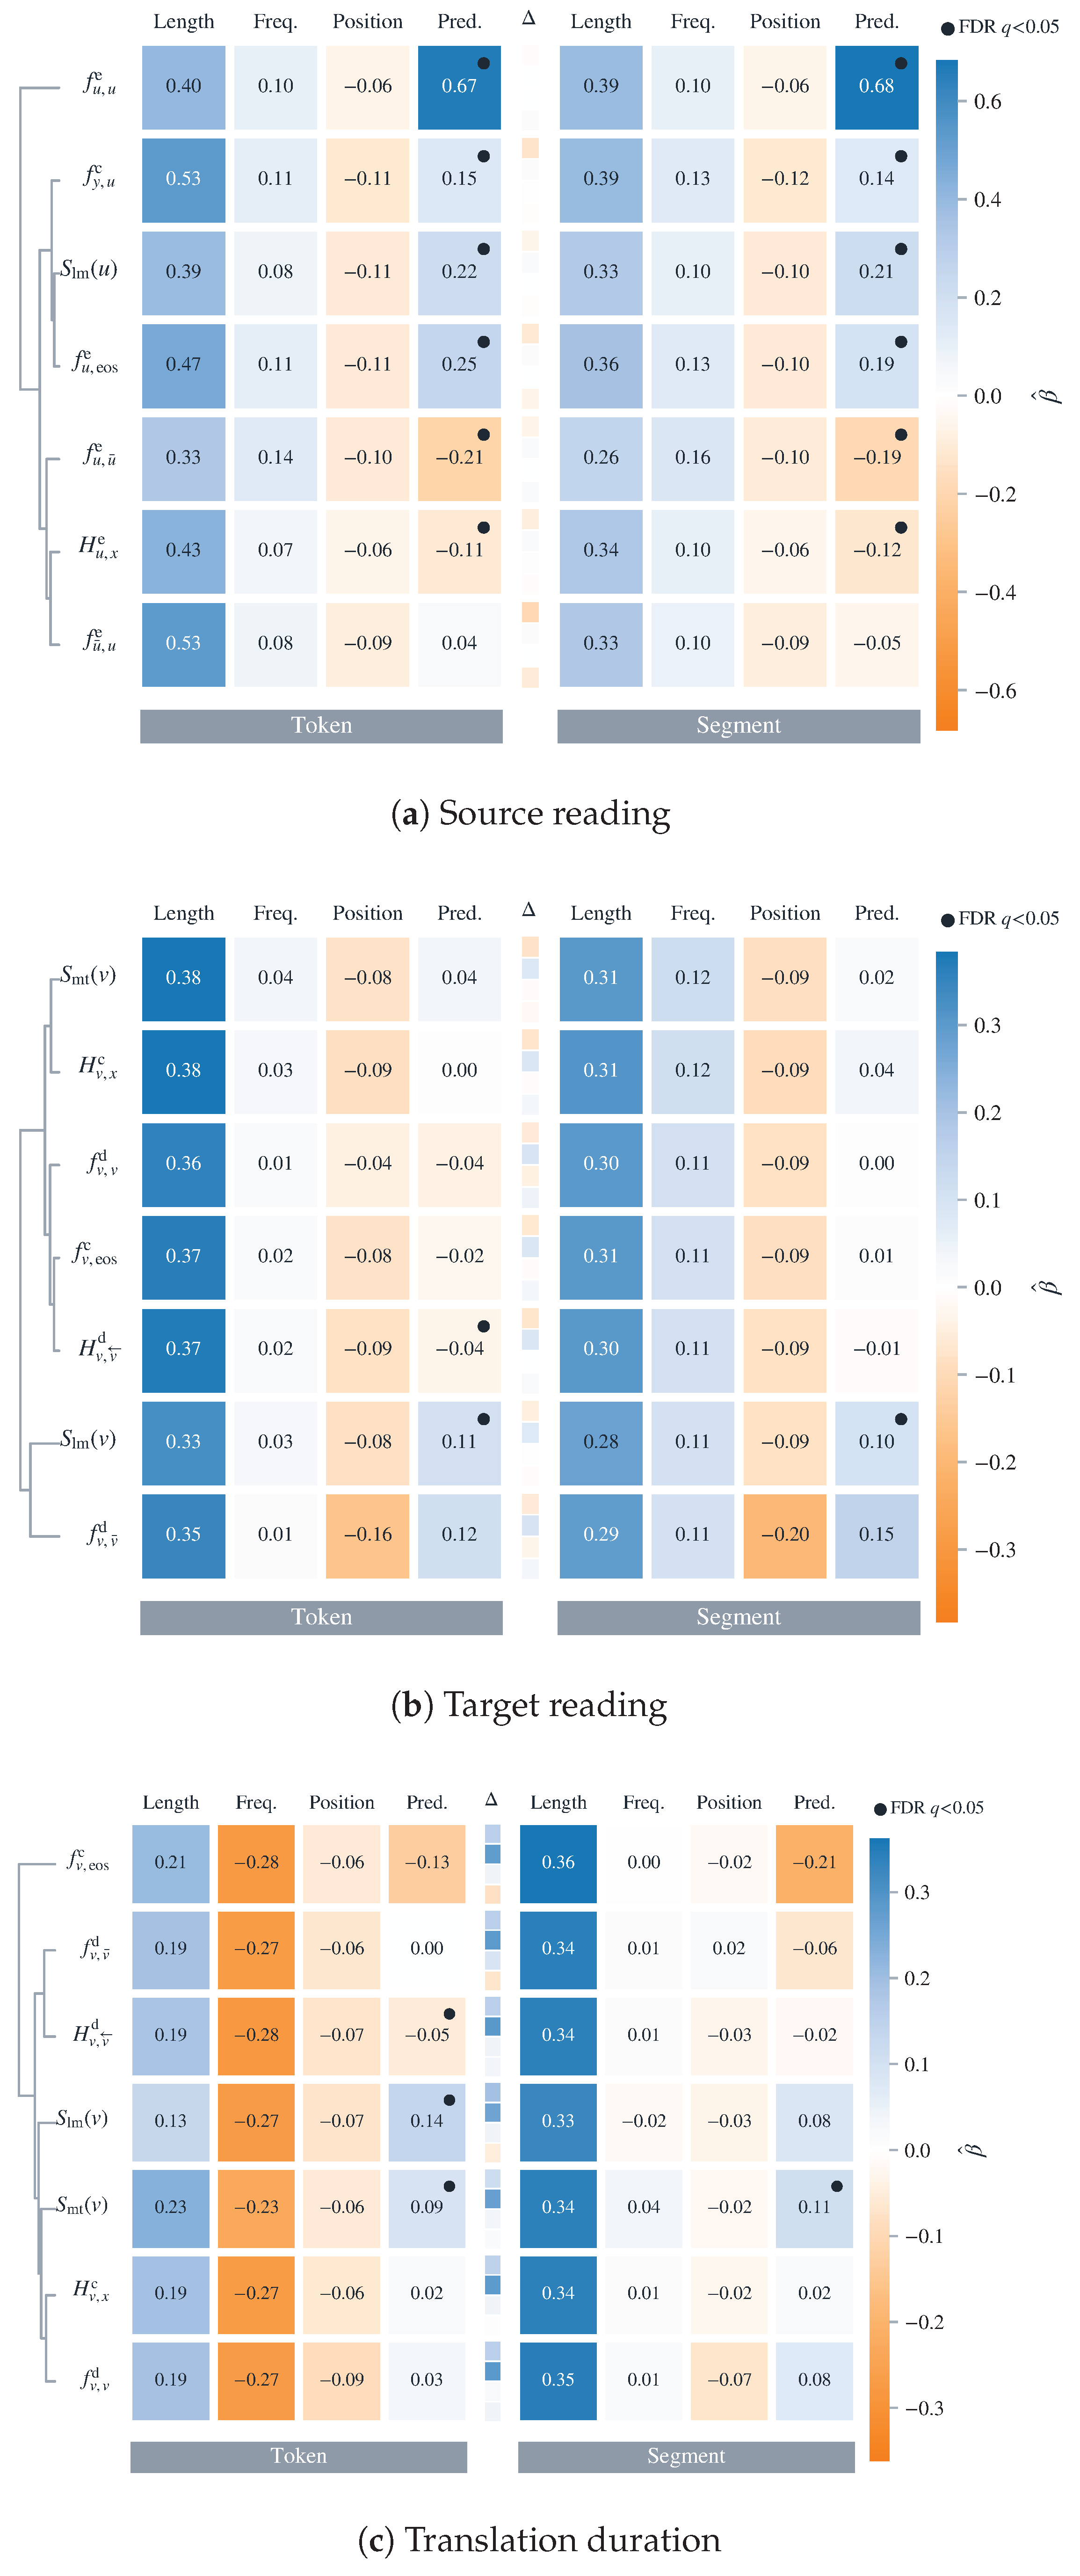
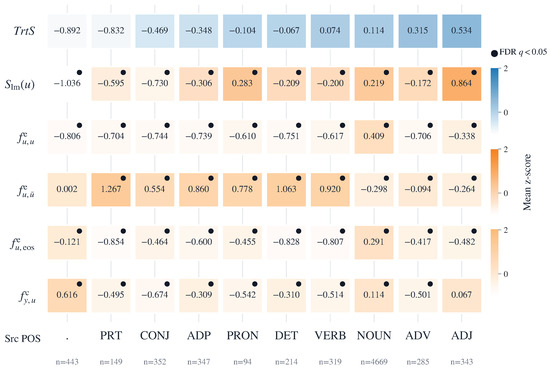
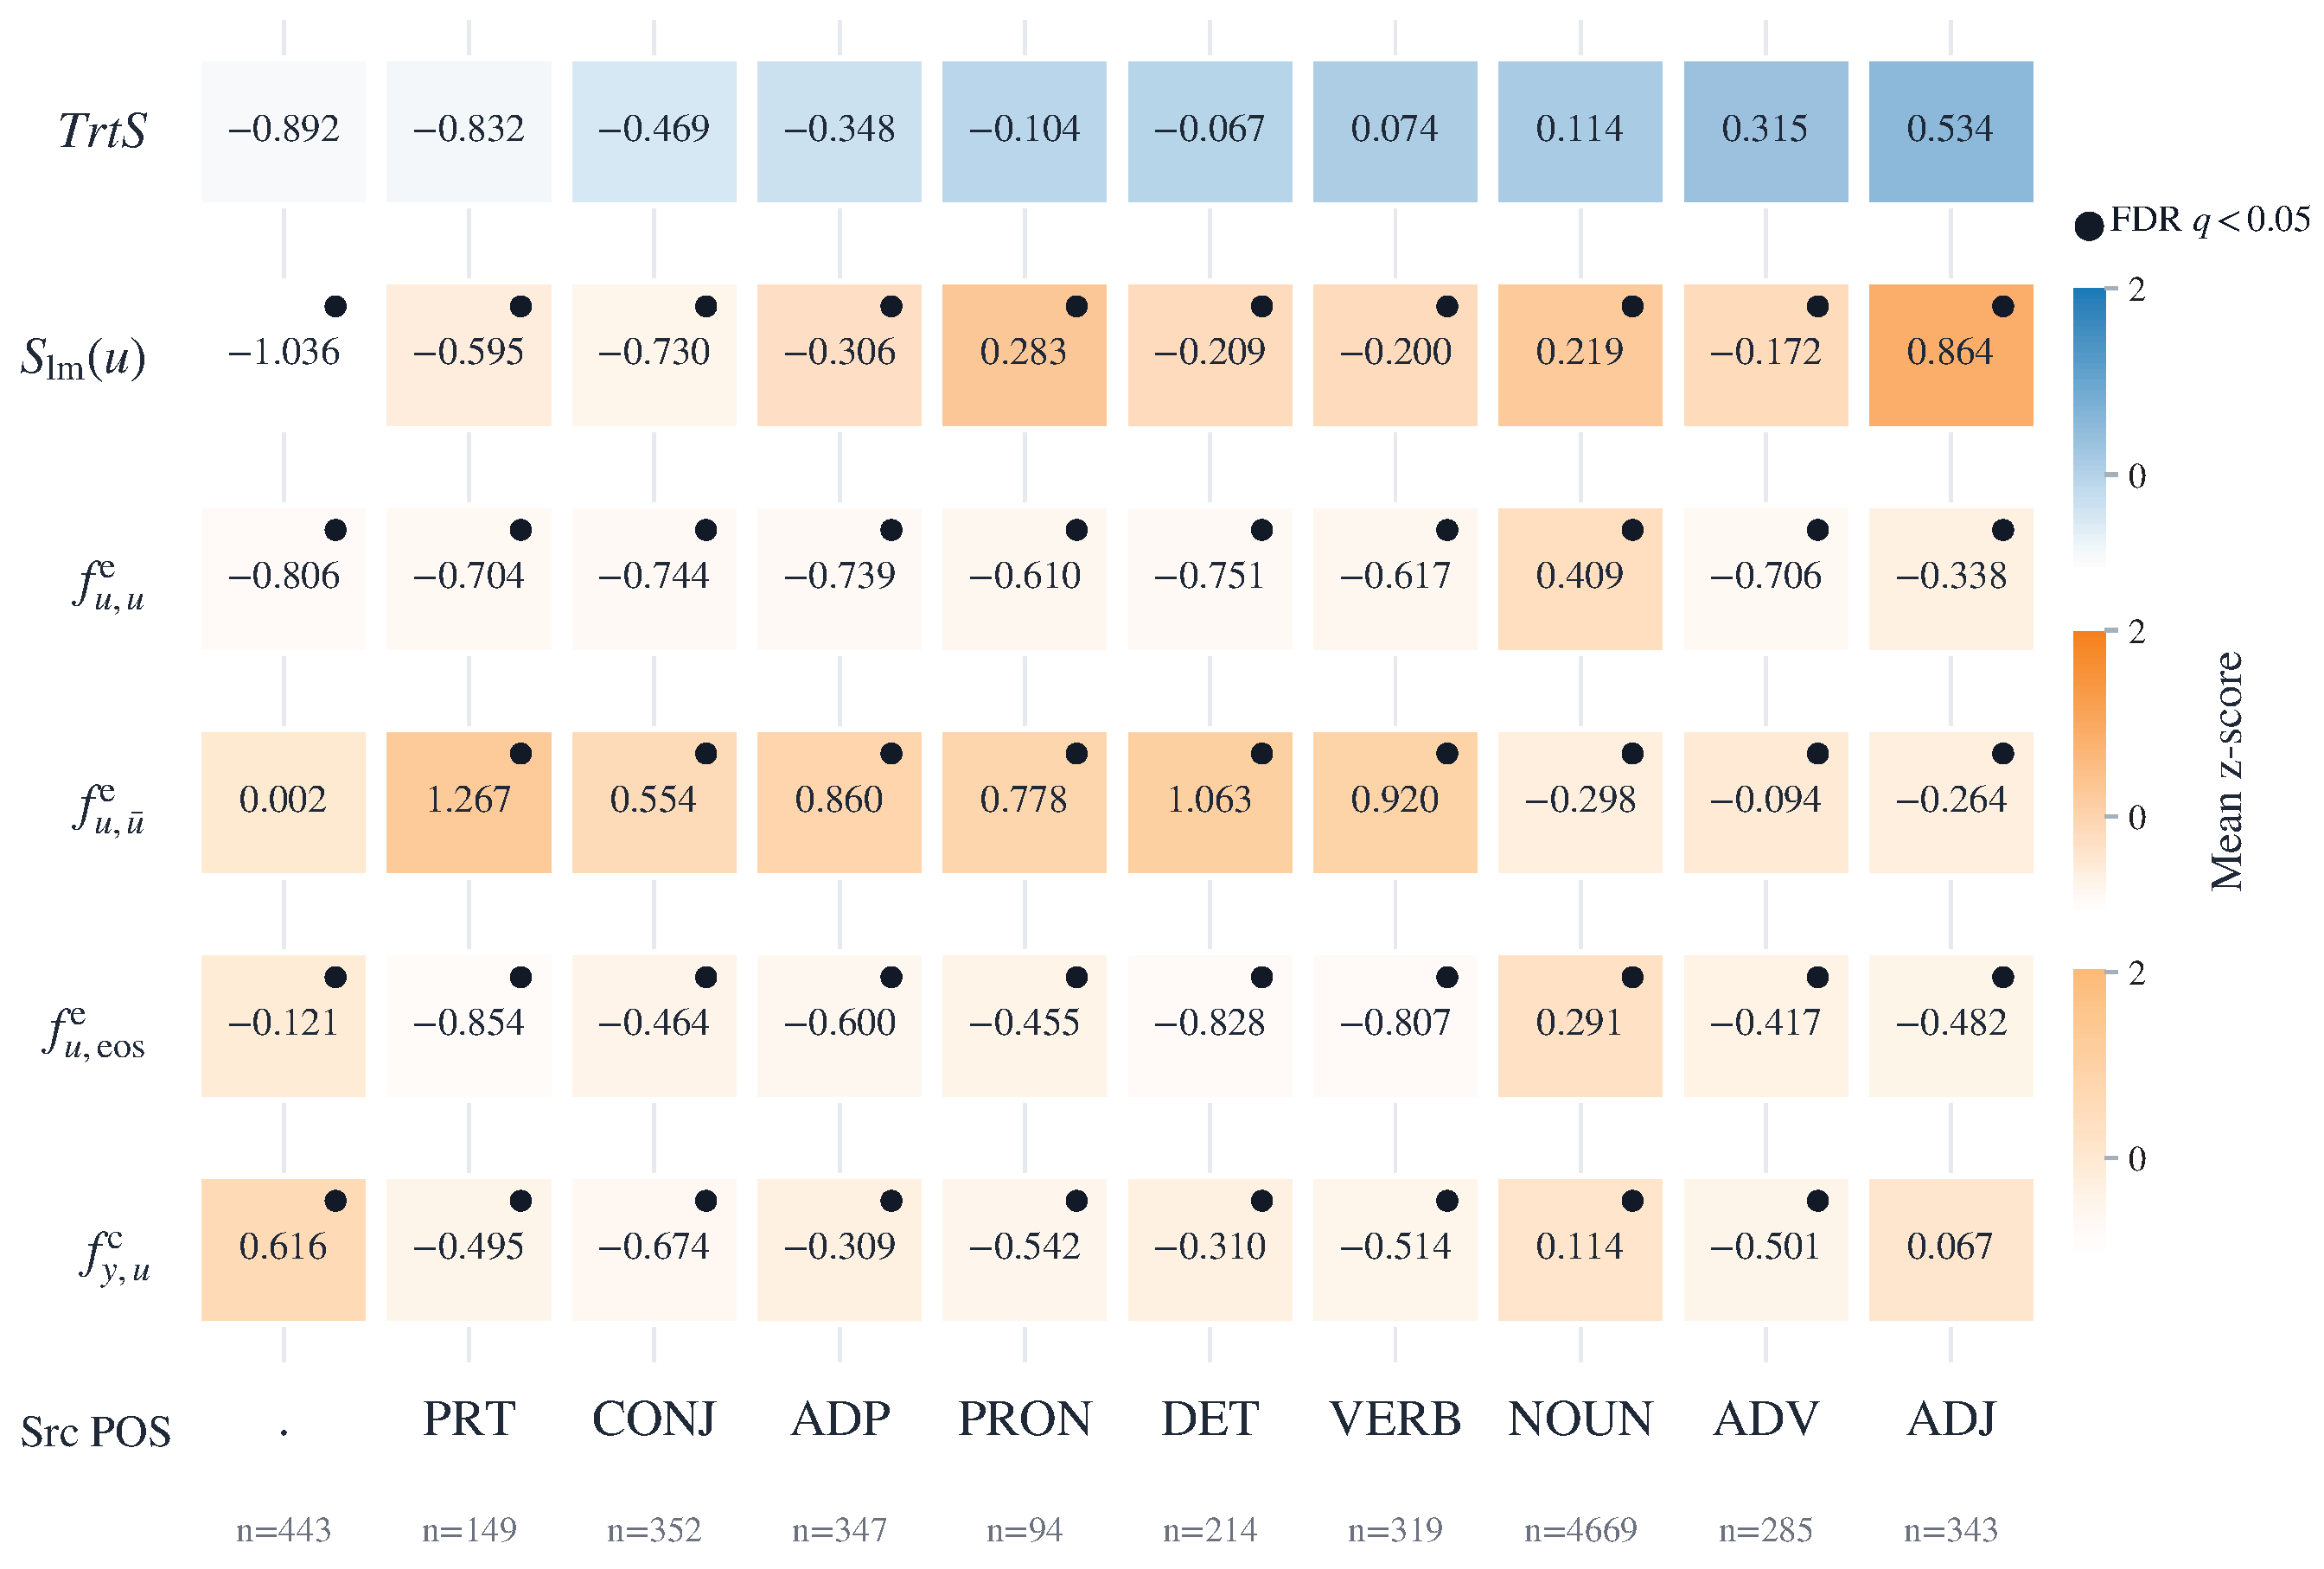
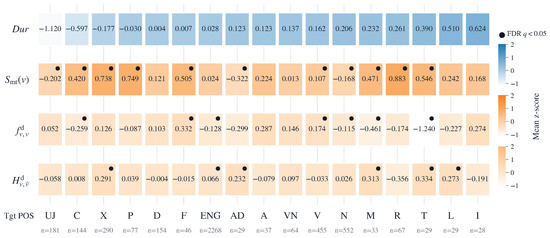
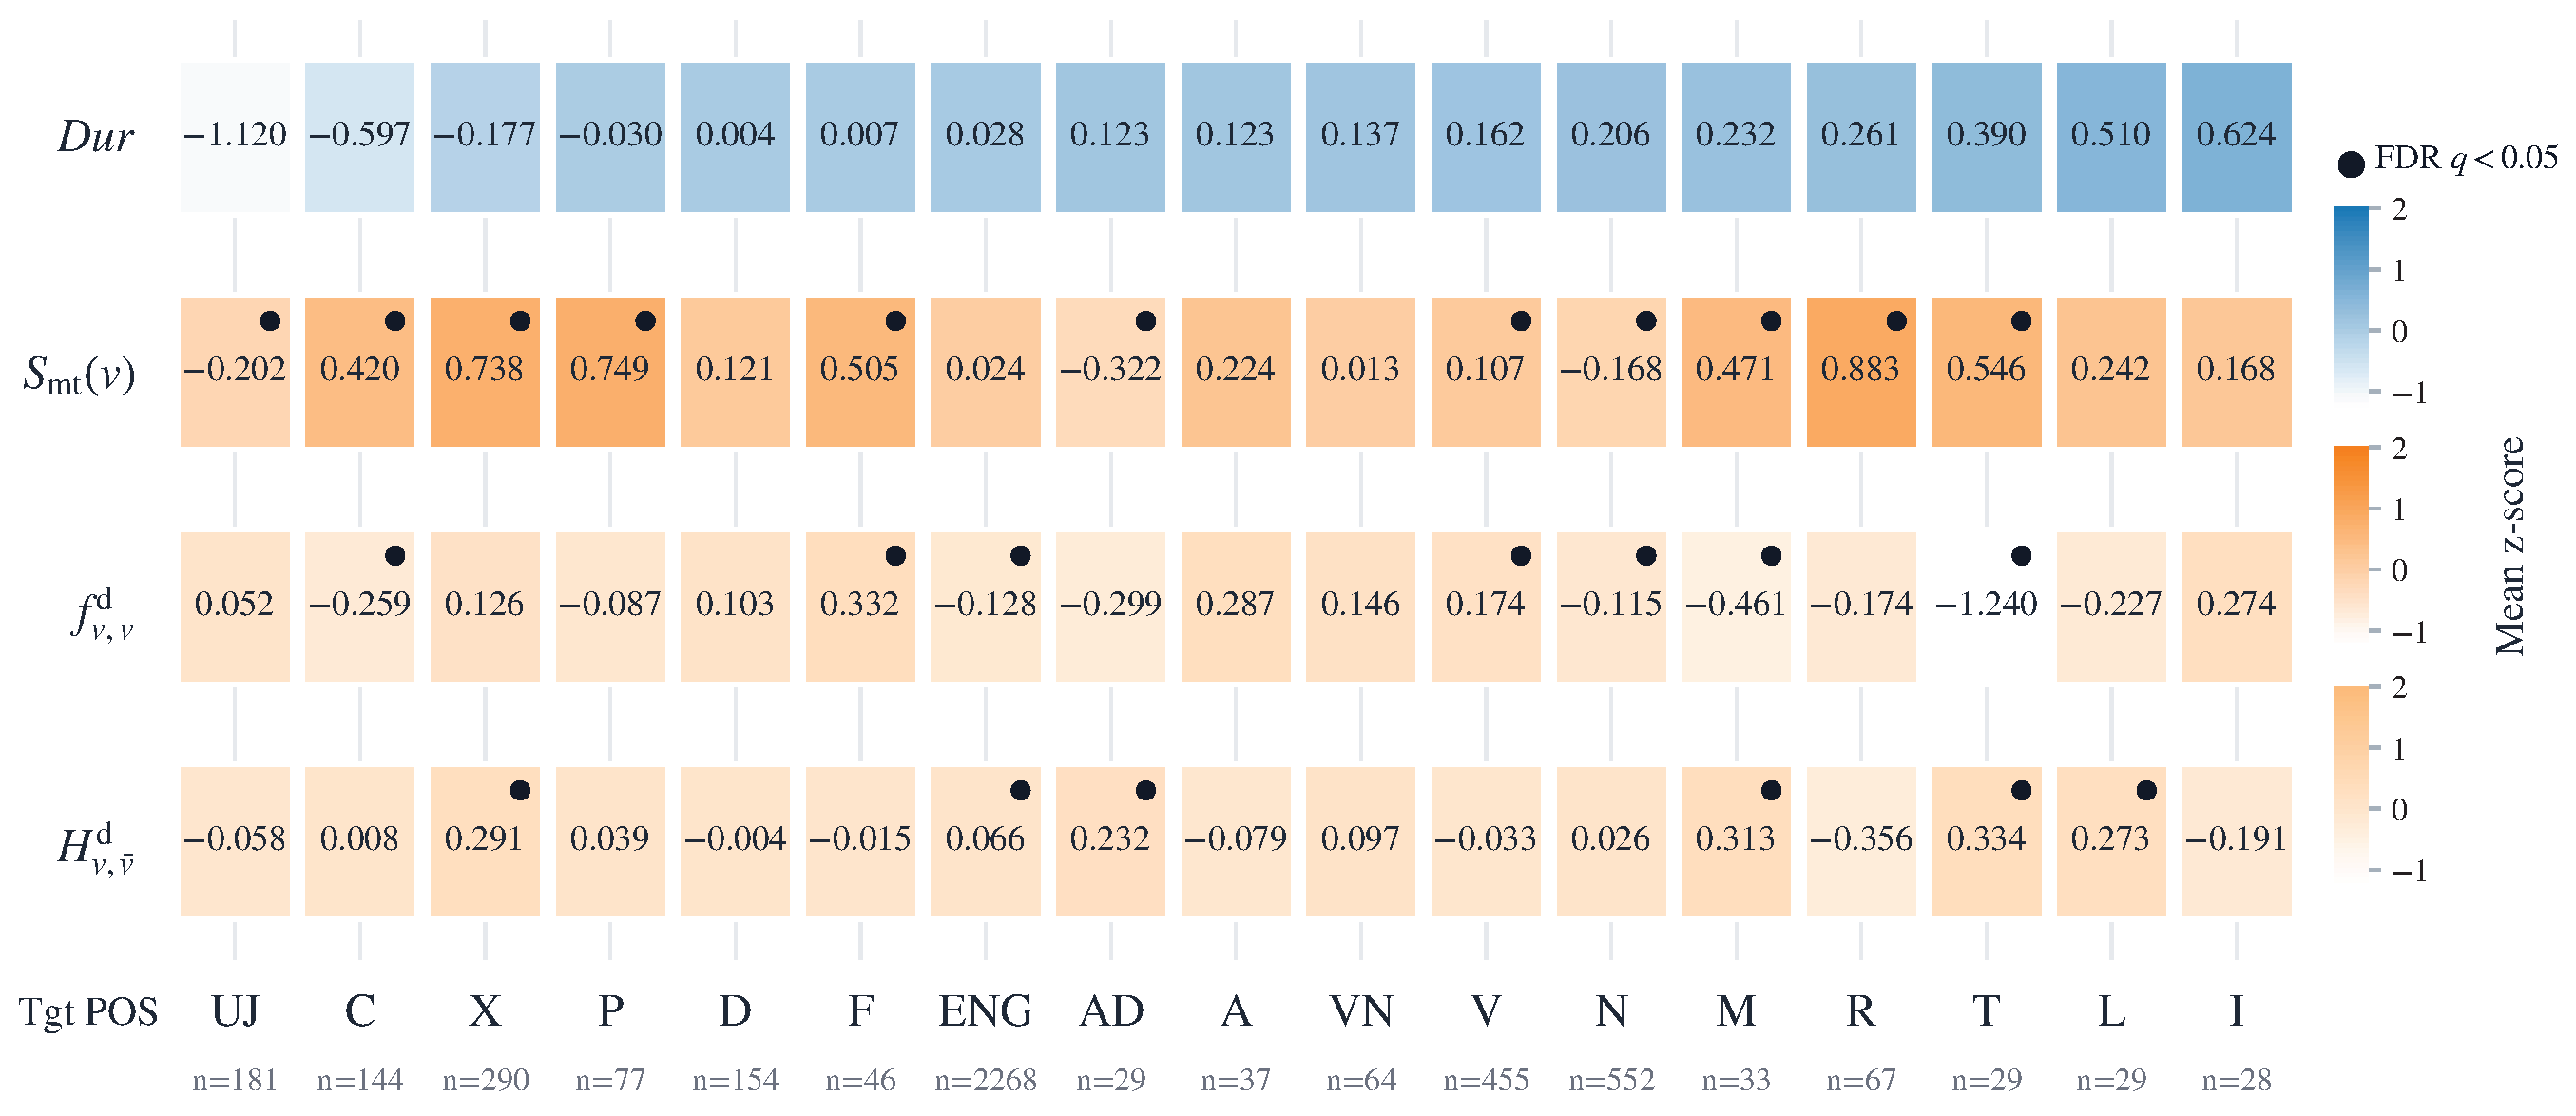
The coefficient estimates in Figure 5 show that these predictors retain interpretable effects after controlling for segment length, word frequency, and within-sentence position, under the maximal random-effects structure described above. A part-of-speech breakdown further reveals that source-side predictor effects were largest for content words (adjectives, nouns), while target-side effects were more evenly distributed across POS categories, reflecting the mixed reading and production processes that target duration captures (Figure 6 and Figure 7).
Figure 5.
Coefficient estimates for TrtS, TrtT, and Dur. Each heatmap shows the control terms and the predictor for token- and segment-level models.
Figure 6.
POS summaries for source reading. Larger values indicate POS categories for which model-derived predictors explain more variance in source reading time.
Figure 7.
POS summaries for target reading and duration. The target-side pattern is more dispersed than the source-side pattern, consistent with the mixed reading and production character of target behavior.
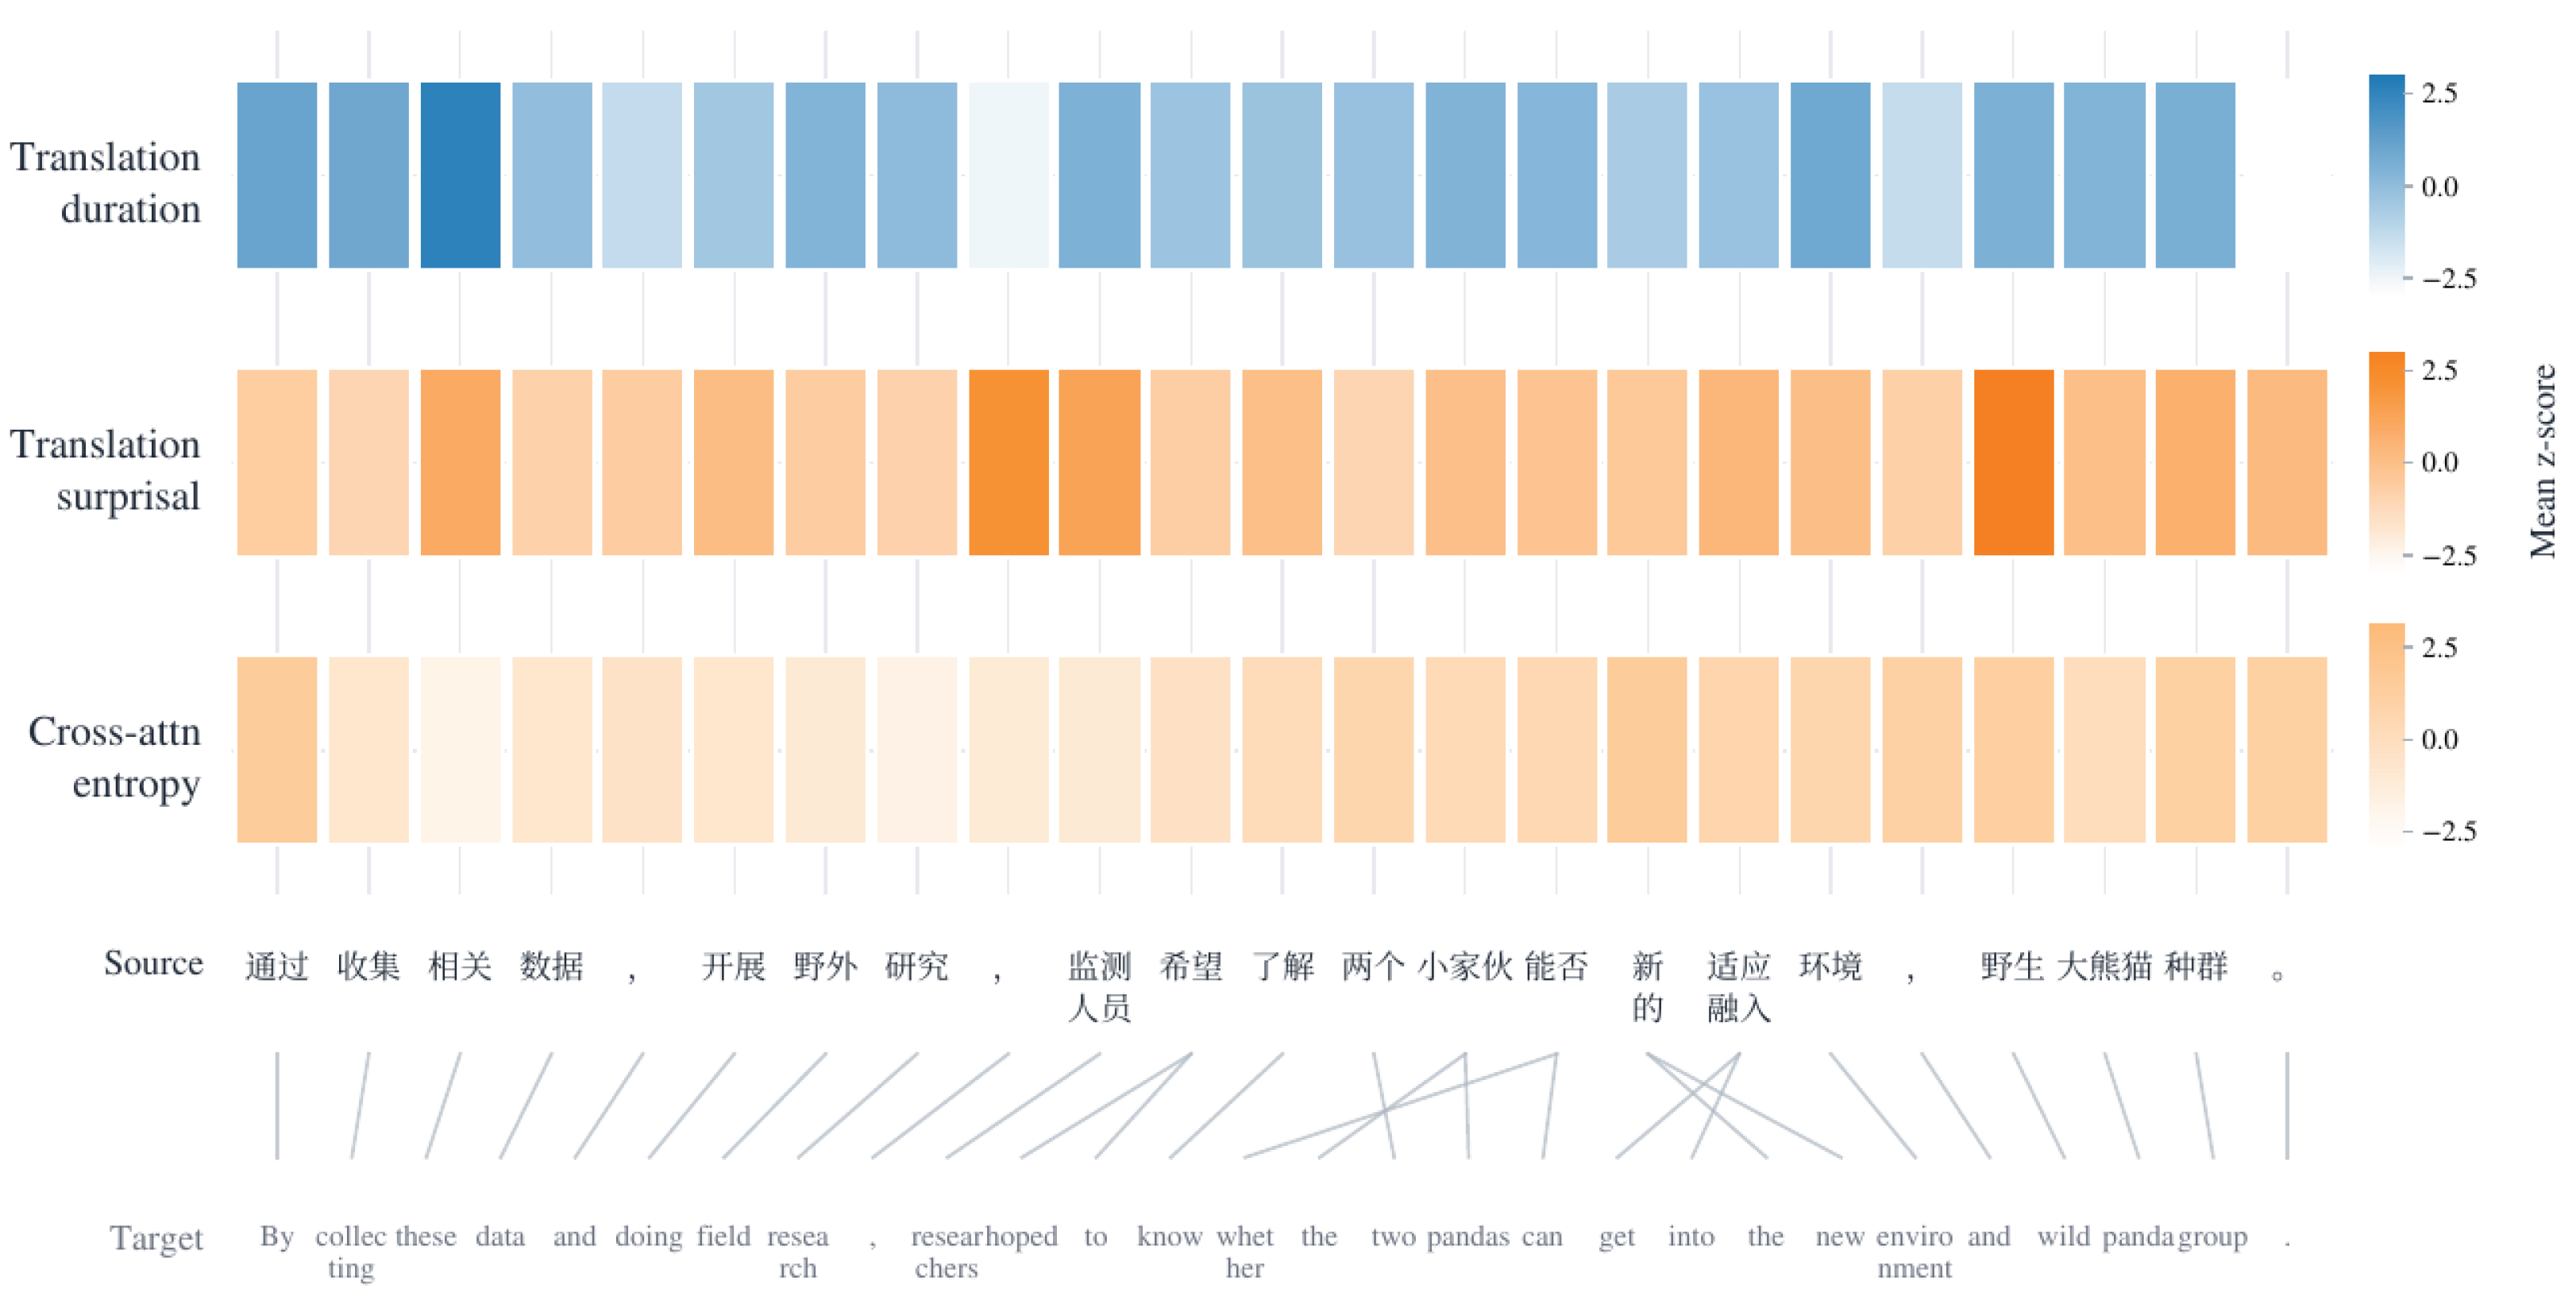
Figure 8 illustrates the alignment between source and target tokens for an example sentence, showing how standardized duration, translation surprisal, and cross-attention entropy map onto a common source–target alignment.
Figure 8.
Aligned unit example comparing standardized human duration, translation surprisal, and cross-attention entropy.
4.2. Task, Direction, and Interaction Effects
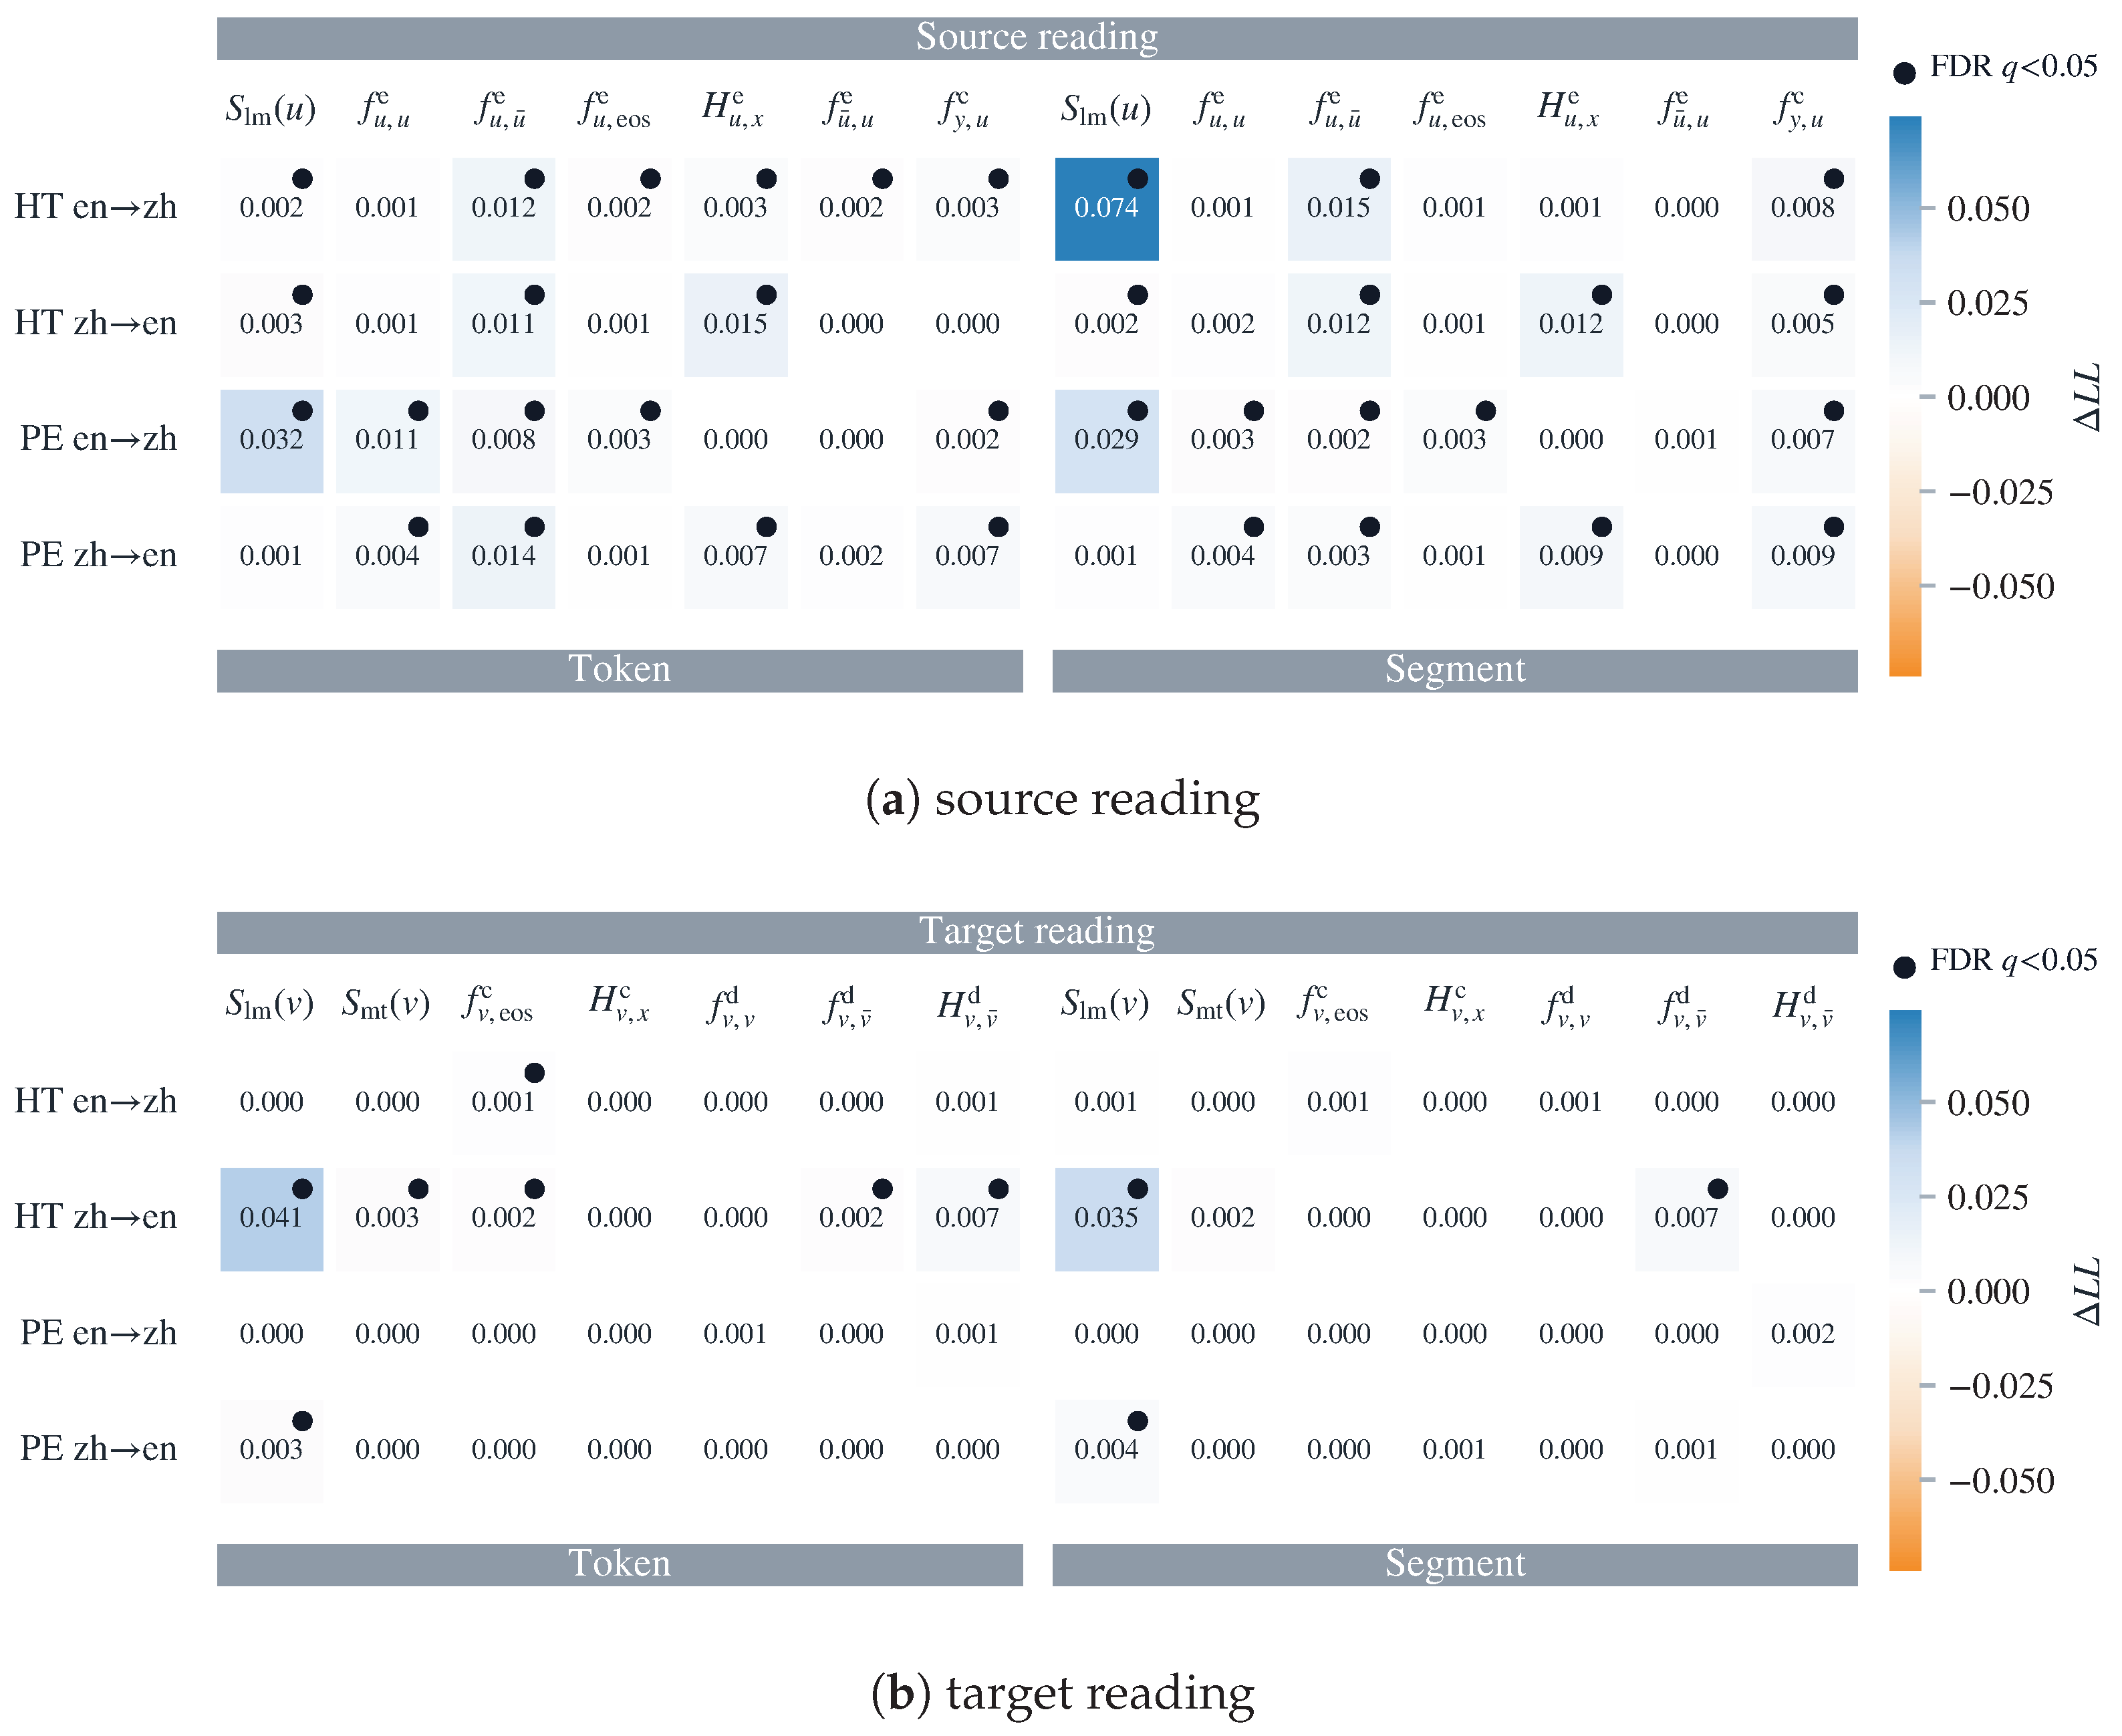
The grouped summaries show that direction produces broader changes than task type (Table 3). en→zh has stronger source reading effects, whereas zh→en has stronger target reading effects; duration effects are comparable across directions. Because the direction split is so pronounced, target-side effects can be larger within a single direction or task than in the pooled sample, where opposing directional patterns partly cancel. Translation and post-editing differ most clearly on target-side measures, but post-editing does not eliminate predictor effects: source reading remains highly predictable in this task, even though target reading predictors lose significance there. Figure 9 shows the full predictor-level breakdown across the four task-by-direction conditions.
Table 3.
Group mean and number of predictors reaching FDR significance out of 14 tested token/segment combinations.
Figure 9.
in the four task-by-direction conditions: translation en→zh, translation zh→en, postediting en→zh, and post-editing zh→en.
The pooled interaction models show that direction modulates predictor effects more broadly than task type: direction interactions reach FDR significance for 18 of 42 predictor comparisons, and task interactions for 7 of 42. The largest direction interactions involve for source reading and for both target reading and duration. Task interactions, although fewer, are not uniformly absent: they reach significance chiefly on target reading, where decoder self-attention entropy interacts with task type at both levels (Table 4; Figure 10).
Table 4.
Largest interaction effect for each outcome. Positive indicates improved fit relative to the corresponding additive mixed model; p is the likelihood-ratio p-value, and q is the FDR p-value.
Figure 10.
Predictor × task (top) and predictor × direction (bottom) interaction. measures improvement from adding the interaction term to the additive mixed model.
4.3. Temporal Decomposition of Duration
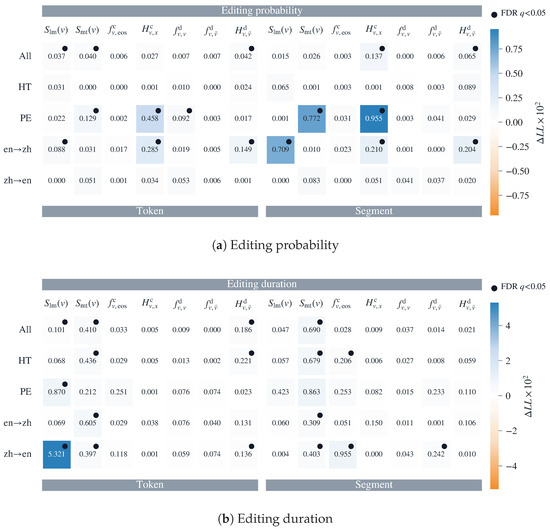
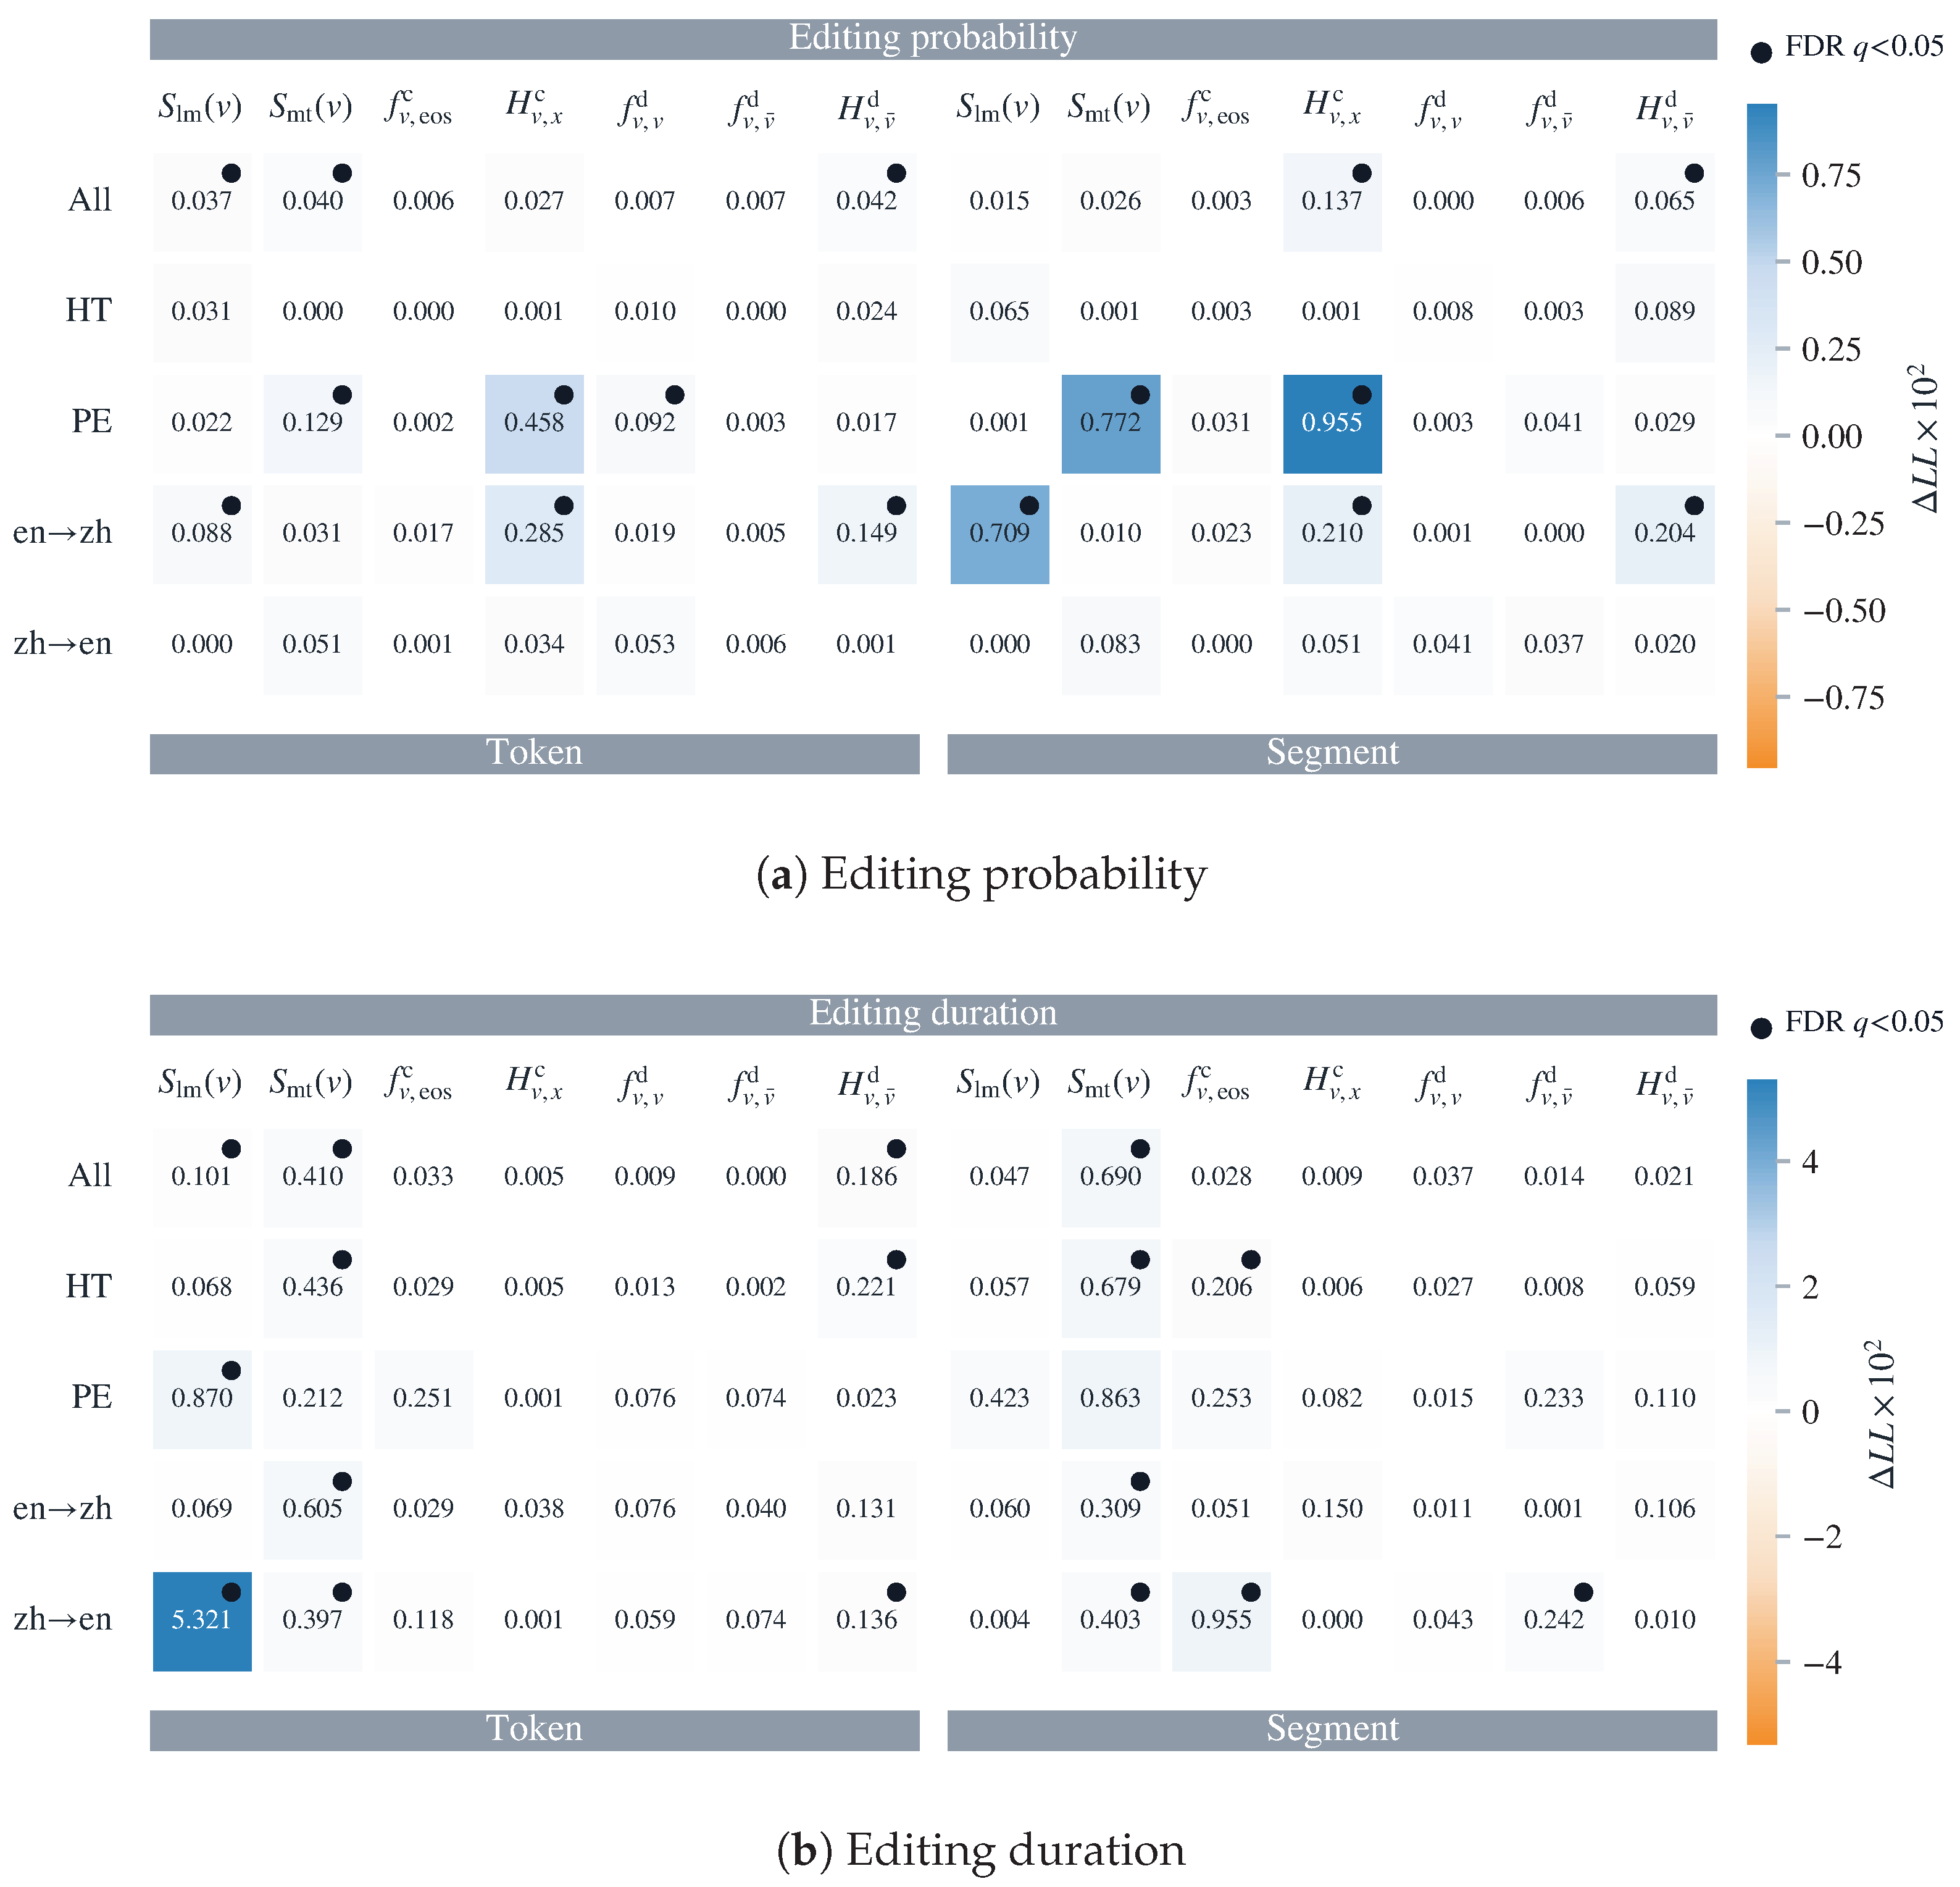
Duration is a production measure that complements the reading measures, but the behavioral processes are not directly observable from gaze. To extend the temporal window from gaze to behavioral response, we treated target duration as a two-stage process. Most aligned units receive zero duration because no gaze was allocated or no editing was triggered. Positive durations reflect how long production persists once initiated. The two-part model therefore decomposes the temporal process into two stages: edit occurrence and conditional editing duration. In the editing probability model, edit occurrence was predicted by a subset of target-side features. Decoder self-attention showed the clearest pattern, while cross-attention contributed mainly at the segment level; LM and NMT surprisal also reached significance in selected token-level comparisons (five of fourteen token/segment comparisons reached significance). A supplementary comparison of features computed from the original drafts used for post-editing showed a direction-dependent pattern: the features distinguished edited from unedited segments in one post-editing text but not the other. In the conditional editing duration model, NMT translation surprisal was the strongest predictor of editing time among units that were actually edited, with target LM surprisal and decoder self-attention entropy also significant (Figure 11).
Figure 11.
Two-part duration model. (a) Edited or not (logistic GLMM); (b) edit duration (LMM).
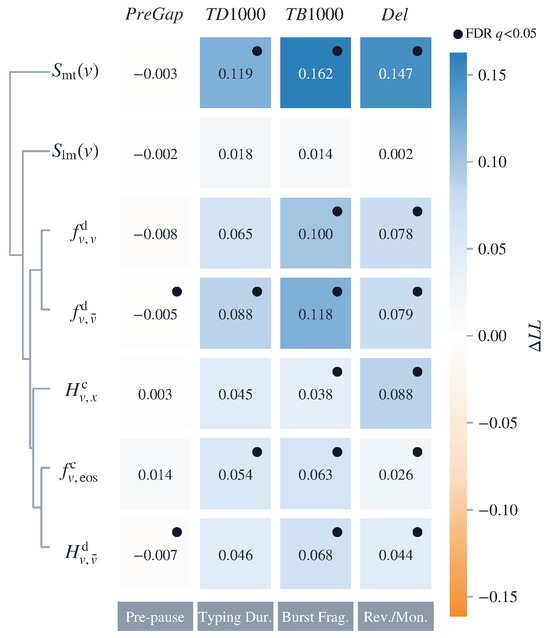
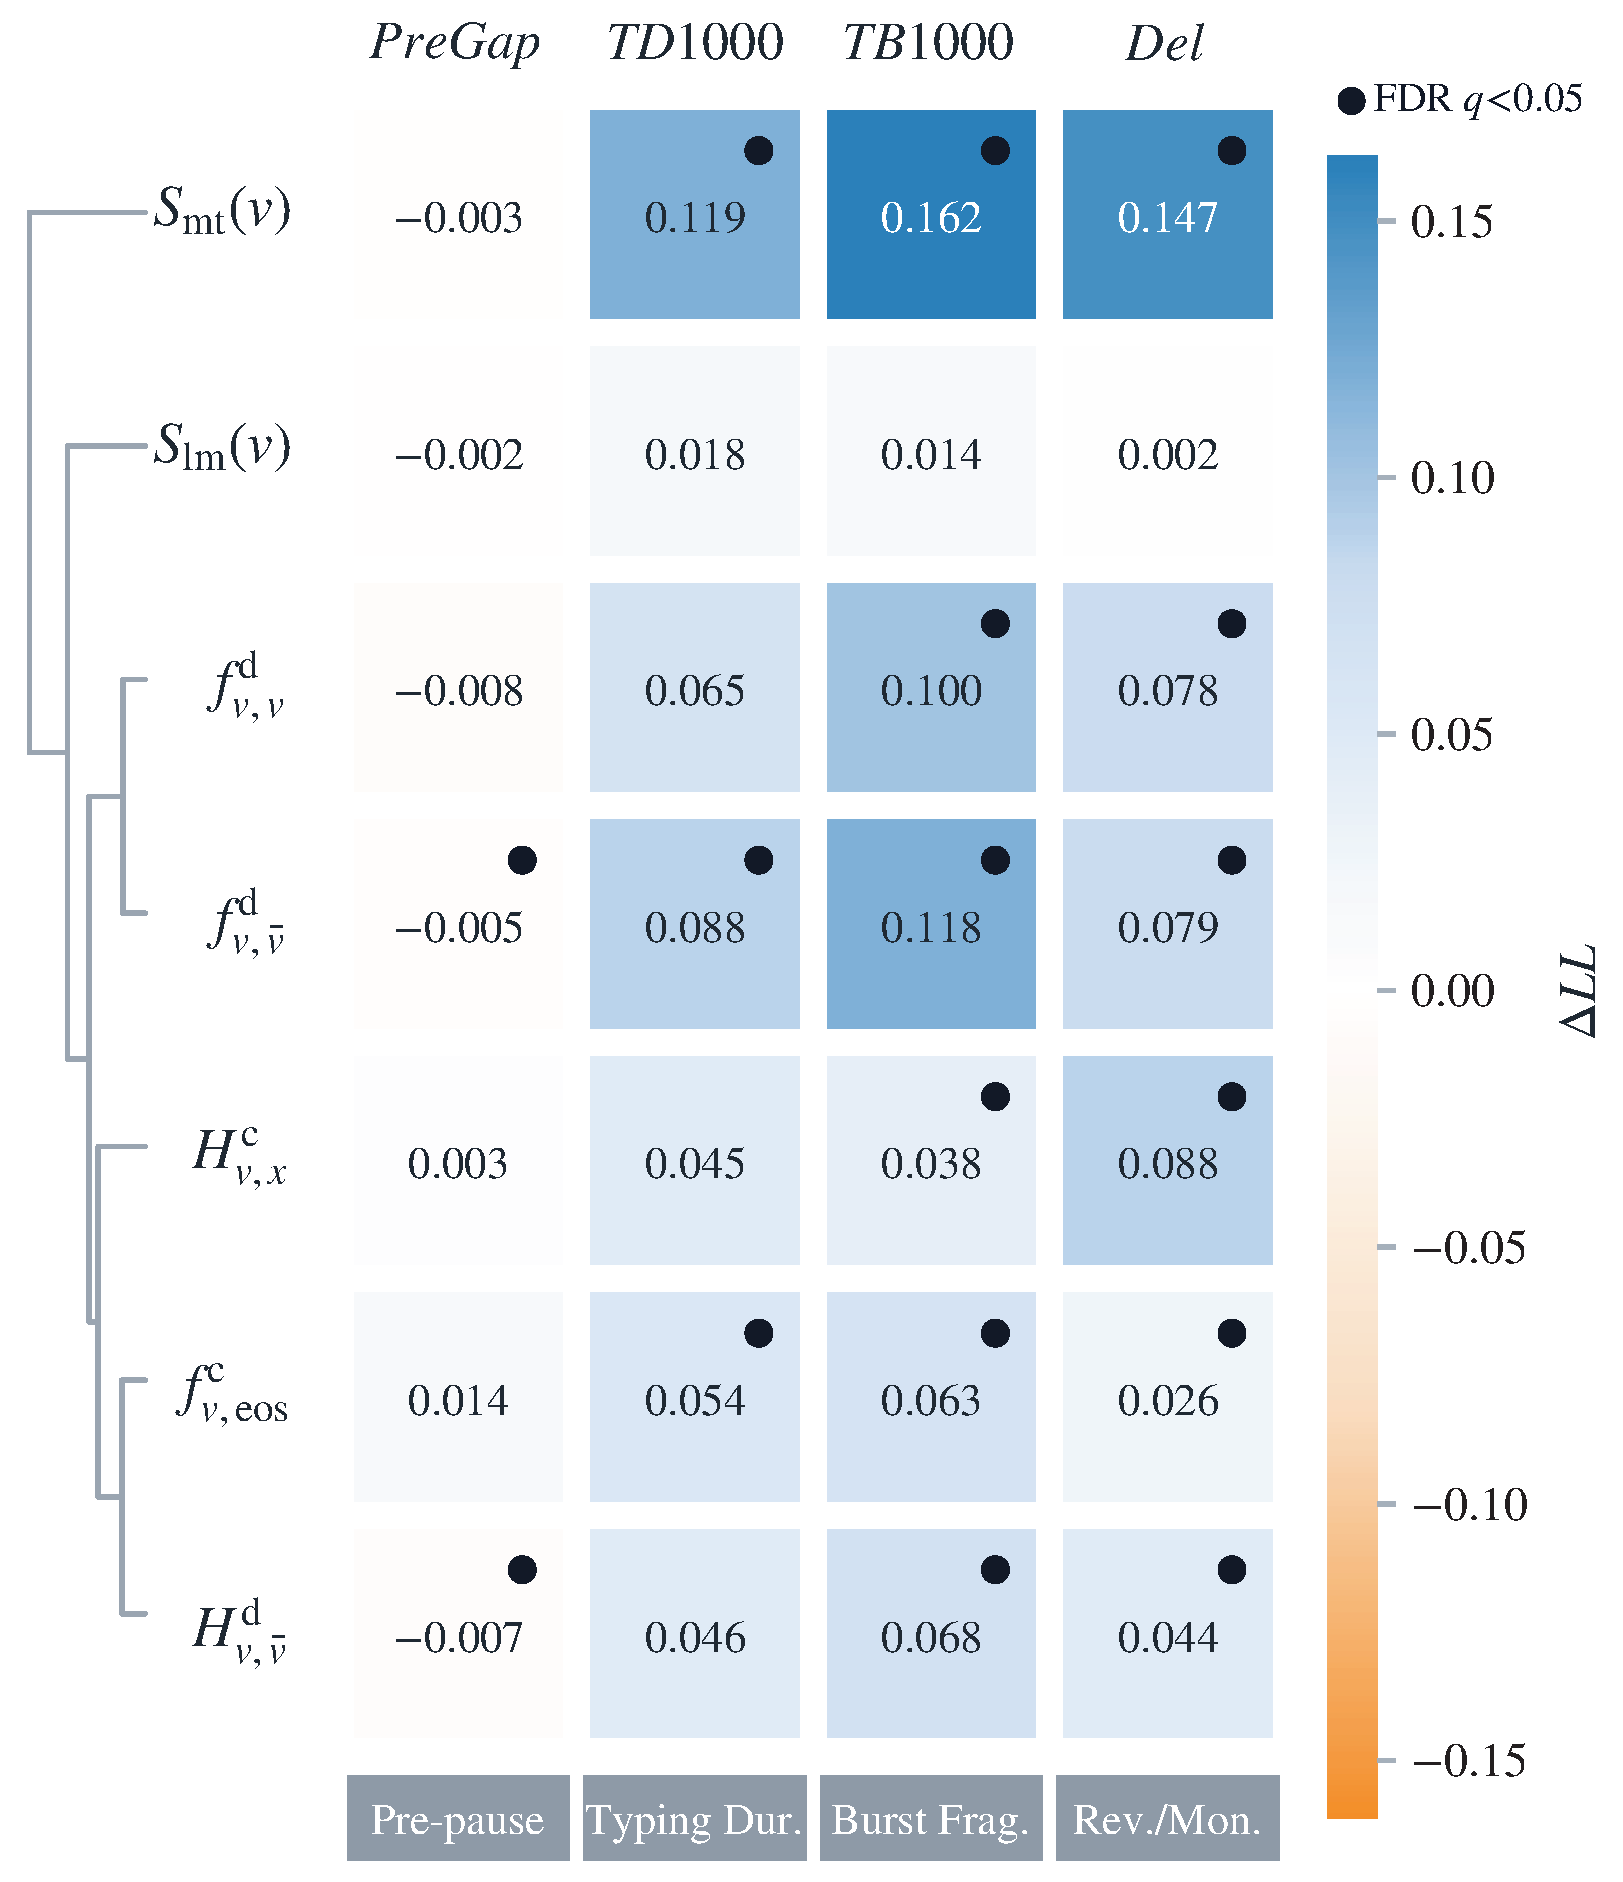
To further interpret the duration component, we decomposed positive duration into four key-logging measures from the CRITT TPR-DB segment-level variables [6]: pre-pause (PreGap, the pause duration preceding the first keystroke, which we label as Pre-pause); typing duration (TD1000, the production time within a segment excluding pauses longer than 1000 ms between keystrokes, which we label as Typing Dur.); burst fragmentation (TB1000, the number of continuous keystroke sequences within a segment separated by pauses longer than 1000 ms, which we label as Burst Frag.); and revision or monitoring (Del, the number of deleted characters, which we label as Rev./Mon.). These measures map the temporal process onto specific motor and cognitive operations. NMT translation surprisal is the leading predictor of typing duration, burst fragmentation, and deletion effort, while decoder-side attention features contribute across all four measures, with planning pauses showing a distinct negative association with decoder continuation features (Figure 12). This decomposition indicates that production duration reflects multiple distinct behavioral processes.
Figure 12.
Key-logging for target duration decomposition.
4.4. Residual Contribution of Attention Features
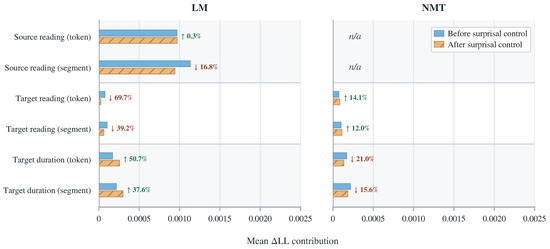
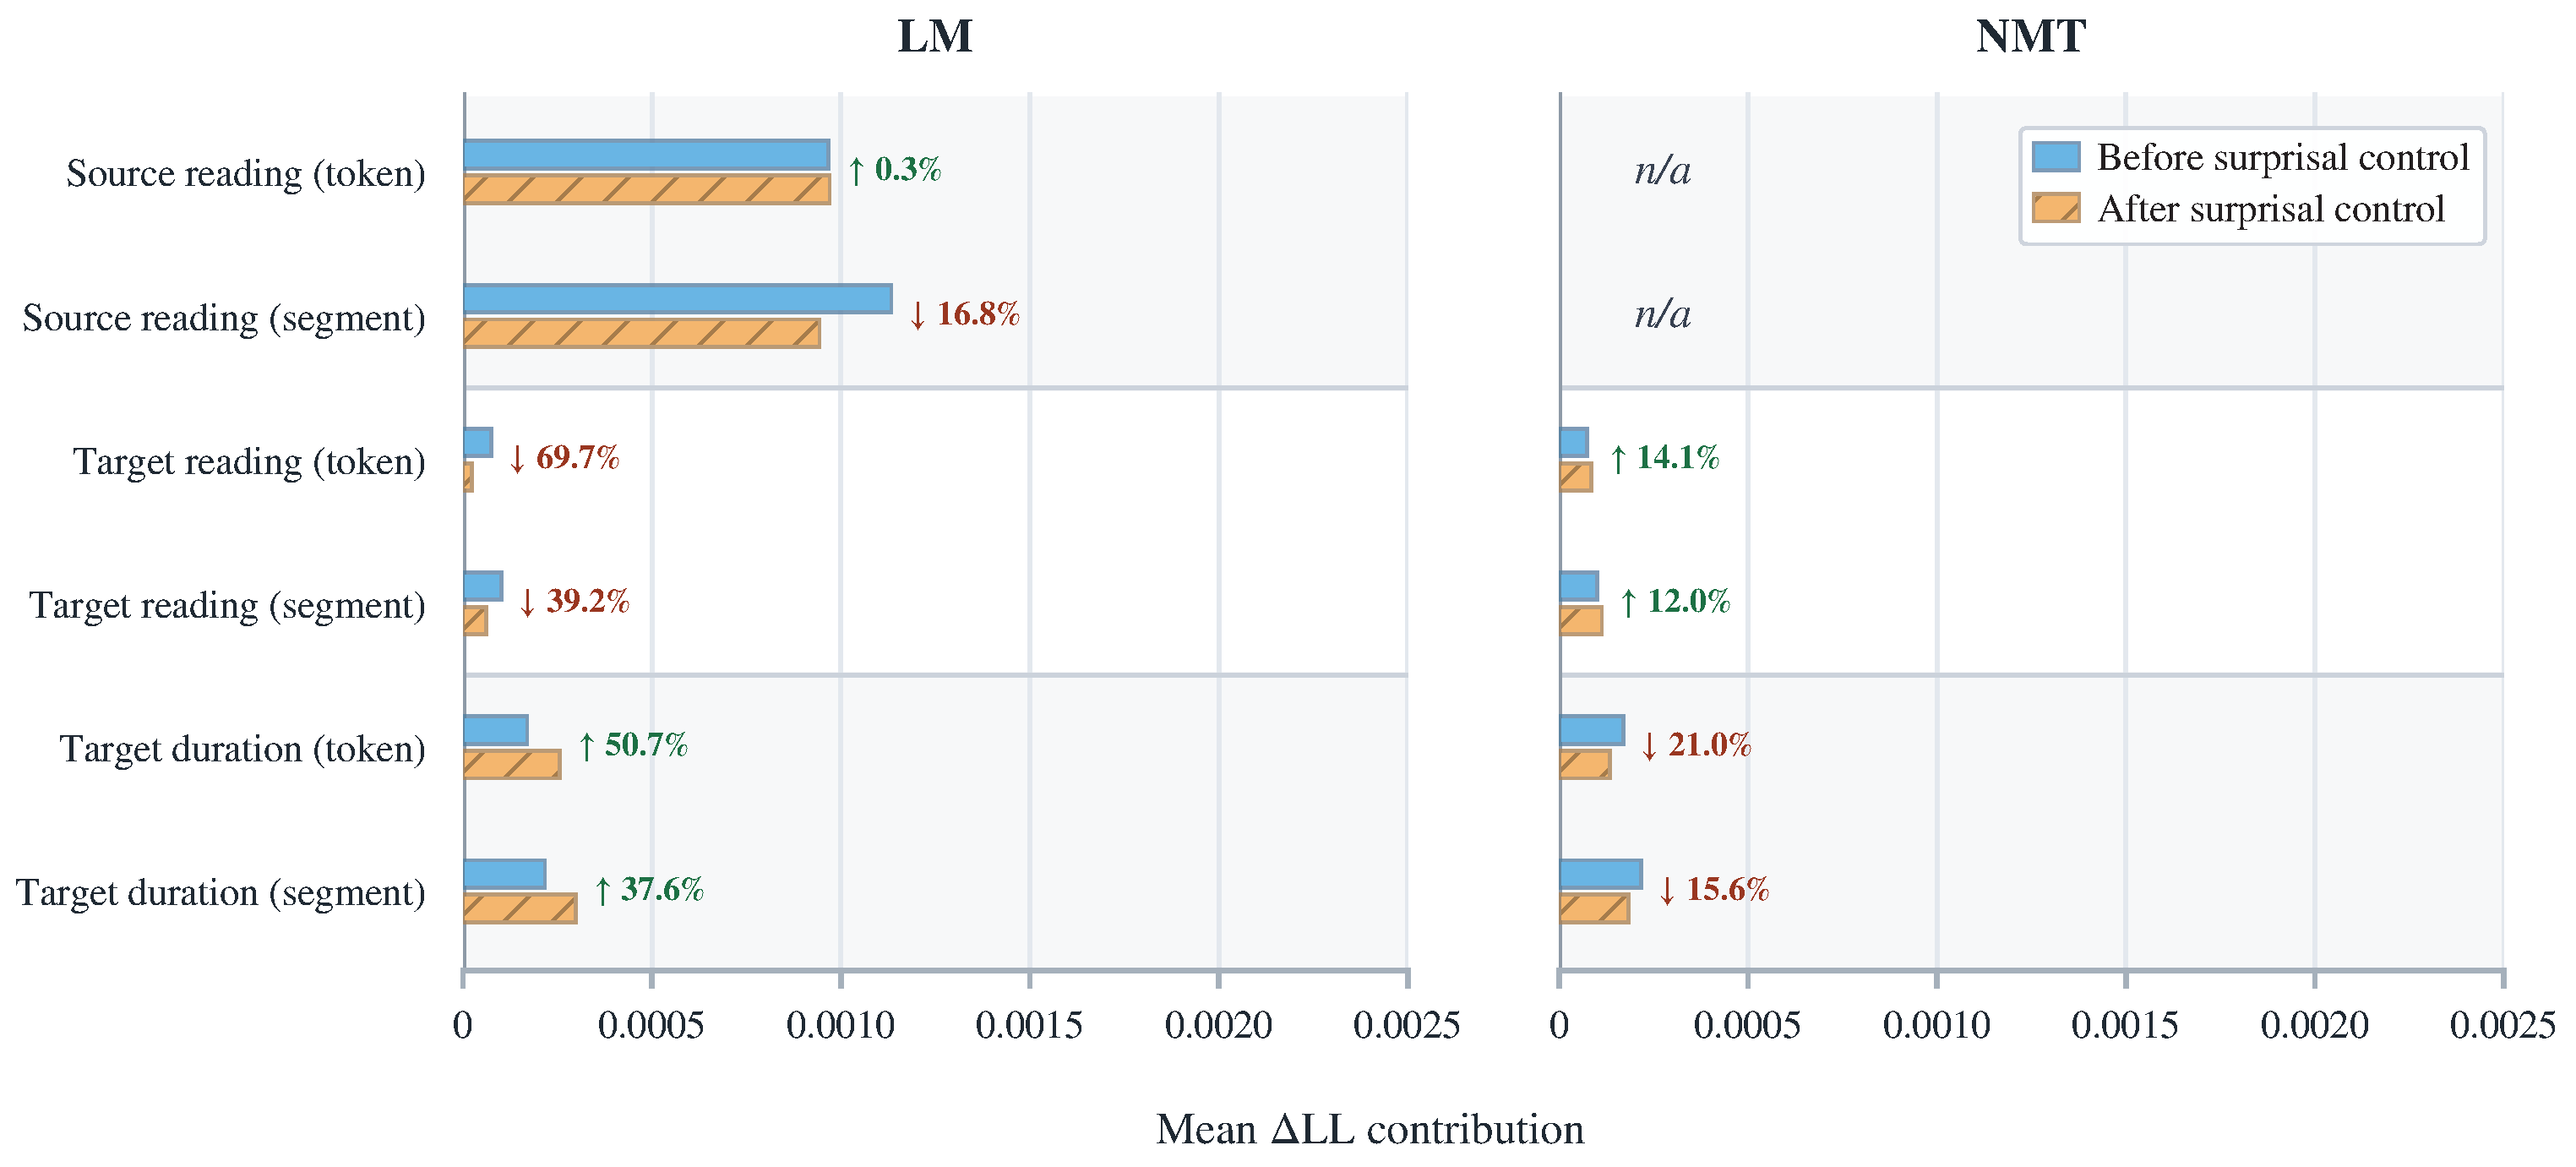
To quantify how much attention features contribute beyond surprisal, we define A as the log-likelihood gain from adding attention features to a baseline model, with computed before surprisal included and computed after. To keep and on a comparable scale, both were computed under the same random-effects structure for a given feature, and Figure 13 plots against for the features that reached the maximal structure. In source reading, the attention contribution stays positive after source surprisal is included: it is essentially unchanged at the token level (from 0.00097 to 0.00097) and decreases at the segment level (from 0.00113 to 0.00094). Target-side attention effects are substantially smaller overall. For target duration, is comparable to or exceeds for some predictors, suggesting that target production and revision contain structure beyond what surprisal captures.
Figure 13.
Paired comparison of mean attention feature before and after surprisal control. Arrows indicate the relative change in contribution.
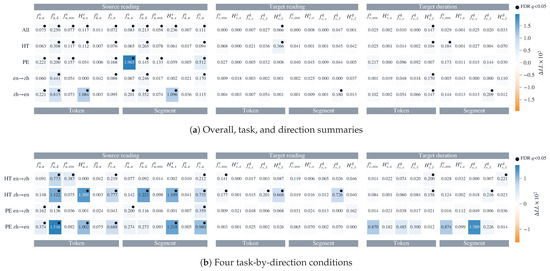
The residual attention patterns further differ by task and direction (Figure 14). Source-side attention effects remained positive after surprisal control, whereas target-side attention contributions were smaller and more condition-dependent. For target duration, the largest residual attention values appeared descriptively in zh→en post-editing, but these effects should be interpreted as exploratory because they did not reach FDR significance.
Figure 14.
Residual attention after controlling for surprisal. (a) Overall, task, and direction summaries, with values scaled by ; (b) four task-by-direction conditions.
5. Discussion
5.1. Monolingual Predictability in Bilingual Reading
The pattern across outcomes suggests a division of labor between monolingual expectancy and bilingual generation uncertainty. Cumulative reading measures were mainly aligned with LM-based predictability, especially for target reading, whereas target production duration showed stronger sensitivity to NMT translation surprisal when target units were aggregated at the segment level. Source reading occupied an intermediate position: encoder self-attention focus was the strongest predictor, while source LM surprisal remained a robust secondary predictor. This dissociation indicates that translators’ eye movements are not simply tracking source-conditioned translation uncertainty. Instead, cumulative reading appears to reflect incremental expectancy within the currently processed text stream, whereas source-conditioned uncertainty becomes more visible when reading is coupled with target production and revision. This interpretation is consistent with the incremental nature of eye movement processing, in which fixation durations reflect difficulty during reading [1,17], and with surprisal accounts in which processing cost scales with predictability [14,15,27].
These findings do not imply that translation reading is functionally monolingual. Cross-language co-activation during bilingual word recognition can be modulated by task context [60]. Evidence from bilingual sentence reading likewise suggests that lexical access is not fully language-selective, as shown by cognate facilitation even in a strongly unilingual sentence context [21]. Reading for translation requires more working memory resources than reading for repetition [4], and target language lexical and syntactic properties can be activated during source language processing [61]. These results refine earlier work: translation reading remains bilingual in task structure and available lexical activation, but cumulative reading times are more strongly indexed by monolingual predictability than by translation uncertainty.
5.2. Direction, Task, and Post-Editing Duration
Direction effects are broader than task effects in both the grouped summaries and the pooled interaction models. This suggests that relations between predictor and reading behavior change more between L1→L2 and L2→L1 than between translation and post-editing alone, consistent with bilingual eye movement research showing that L2 reading typically involves longer reading times and more effortful eye movement patterns than L1 reading [20]. This also fits evidence that lexical frequency effects are stronger in bilingual L2 reading than in L1 reading [62]. Translation direction therefore appears to be more than a difference in overall task difficulty. It appears to shape which predictors are reflected in behavior and how processing demands are distributed across source processing, target formulation, and monitoring.
Task effects were narrower than direction effects but not entirely absent: task interactions reached significance for fewer predictor comparisons than direction interactions, and were concentrated on target reading, where decoder self-attention entropy interacted with task type. This indicates that HT and PE differ only in selected respects in how predictors map onto reading and production measures. Studies of reading have long shown that eye movement behavior varies with task demands, including contrasts among careful reading, comprehension-oriented reading, proofreading, and skimming [18,19]. The comparatively limited task interactions here suggest that translation and post-editing may draw on a largely shared bilingual reading architecture, which would explain why they pattern similarly across most measures.
Post-editing, however, changes the role of the target text: it is not only produced, but also inspected, diagnosed, and selectively edited. The two-part Dur analysis makes a related but distinct point. A target unit must first trigger editing, and only then can positive editing duration be observed. This distinction, between whether and how long editing occurs, operates within the duration measure itself, rather than as a task-level interaction with predictor effects. Under the maximal random-effects specification, edit triggering was predicted by a subset of target-side features, mainly decoder self-attention entropy and surprisal, so both stages are sensitive to model-derived predictability rather than only the conditional duration stage, although edit occurrence is captured more selectively than editing duration. This yields a methodological implication: Dur should not be interpreted as a single continuous proxy for production effort. In post-editing, it combines at least three separable processes: whether editing is triggered, how long production continues once triggered, and how revision unfolds through typing bursts, deletions, and pauses. Key-logging results support this interpretation by showing that target duration draws on typing duration, burst fragmentation, deletions, and pre-pause time rather than a single effort dimension. This fits evidence that post-editing effort varies across indicators [63], depends on MT error type [64], and may diverge across product and process measures [65]. Weaker or more selective predictor links in post-editing should not be taken as evidence of reduced cognitive involvement; a more plausible interpretation is that revision-dominated behavior is less well captured by predictors derived from continuous generative sequences.
5.3. Attention Features and Theoretical Implications
The attention results are clearer under this interpretation. Attention-derived features did not replace surprisal as the primary predictor, but they helped identify where model-internal structure remains behaviorally informative after expectancy is controlled. Their contribution was clearest for source reading and for post-editing target duration, suggesting attention-derived features are best interpreted here not as direct analogs of human attention, but as diagnostics of model-internal organization that may become relevant when translation involves alignment, monitoring, or revision. This interpretation is consistent with work showing that transformer attention patterns can contribute incremental predictive value for reading times [41,42], while also respecting cautions that model attention weights are internal allocation variables rather than transparent explanations of model behavior [66,67]. NMT attention may help explain model predictions while still failing as a straightforward alignment between source and target tokens [43]. Surprisal, by contrast, provides a more reliable link between probabilistic language modeling and cumulative eye movement behavior.
Taken together, these results suggest a graded, reweighted processing system for translation reading. Translators do not switch between a purely monolingual mode and a purely bilingual mode. Rather, bilingual task demands remain available throughout processing, while direction and task type continuously reweight the balance between source comprehension, target formulation, and monitoring. Within that shifting system, cumulative eye movement measures are primarily indexed by incremental monolingual expectancy, whereas bilingual translation uncertainty becomes more visible when reading is coupled with target production and revision. This pattern is also consistent with the residual attention analysis, where target-duration attention effects were numerically largest in zh→en post-editing, although they did not reach significance. This pattern suggests that revision and monitoring in L2 output editing may contain structure not fully captured by surprisal, but it should be treated as exploratory.
5.4. Limitations
The sample of 26 participants and 104 sessions is typical for eye-tracking translation research but still limits detailed subgroup inference; post-editing direction splits in particular should be treated as estimates with wider uncertainty. Attention features are offline correlates of model behavior rather than online causes of reading behavior, and all effects reflect predictive contrasts rather than causal estimates. The between-text design remains a limitation for interpreting direction and task effects; future studies would benefit from designs that pair larger participant samples with a shared, controlled set of materials.
6. Conclusions
This study examined how predictors derived from multilingual pre-trained models account for translators’ eye movements during translation and post-editing across two translation directions. The findings reveal a functional division between monolingual predictability and bilingual translation uncertainty. Cumulative reading measures were primarily linked to monolingual LM surprisal, whereas target production duration showed additional sensitivity to NMT translation surprisal, especially at the segment level. Source reading was best captured by source-side encoder focus, with LM surprisal remaining a robust secondary predictor. Translation direction further reshaped predictor–behavior relations more broadly than task type, especially on target measures, suggesting that L1→L2 and L2→L1 translation may reweight the balance between source comprehension, target formulation, and monitoring.
These findings refine how translation reading should be characterized. They do not support a simple opposition between monolingual and bilingual reading. Instead, translation appears to involve a bilingual processing ecology in which observable eye movement behavior is continuously reweighted by direction and task demands. Within this ecology, cumulative reading difficulty is more strongly indexed by incremental monolingual expectancy, while bilingual translation uncertainty becomes more visible in production and revision. The two-part duration model and key-logging decomposition further show that post-editing duration combines edit triggering, typing, burst fragmentation, deletions, and pausing rather than representing a single continuous effort measure. Attention-derived features contribute additional but smaller and more condition-dependent predictive value, best interpreted as diagnostics of model-internal organization rather than direct measures of human attention.
More broadly, the findings point toward a temporal view of translation process modeling: rather than treating source reading, target generation, and revision as separate behavioral outcomes, future models should capture these as interrelated processes unfolding over time. Future work could pursue this by deploying pre-trained models of varying scales and architectures to examine when monolingual predictability and bilingual translation uncertainty each become behaviorally relevant across this temporal sequence. Designs incorporating larger and more diverse participant samples, crossed materials, and continuous physiological measures would further allow the cognitive mechanisms of bilingual text production—and what distinguishes reading to translate from translating to read—to be traced with greater resolution.
Author Contributions
Conceptualization, Y.Z. and X.Y.; methodology, Y.Z. and X.Y.; validation, Y.Z.; formal analysis, Y.Z.; investigation, Y.Z.; resources, D.L. and X.Y.; data curation, Y.Z.; writing—original draft preparation, Y.Z. and X.Y.; writing—review and editing, D.L. and Y.Z.; visualization, Y.Z.; supervision, D.L.; project administration, D.L. and X.Y.; funding acquisition, D.L. All authors have read and agreed to the published version of the manuscript.
Funding
The work described in this paper was partially supported by a grant from the Research Grants Council of the Hong Kong Special Administrative Region, China (Project No. PolyU 15603225). Assessing the Effectiveness of AI-Assisted Post-Editing: A Process and Product Study Using Eye-Tracking, Key-Logging, and Performance Evaluation.
Institutional Review Board Statement
The study was conducted in accordance with the Declaration of Helsinki, and approved by the Ethics Committee of China University of Geosciences (Approval No. CUG-WY-2024-01, March 2024).
Informed Consent Statement
Informed consent was obtained from all subjects involved in the study.
Data Availability Statement
The data in this study are available from the corresponding author upon request. The data are not publicly available due to privacy considerations.
Acknowledgments
The authors thank the participants for their time and willingness to contribute to this study.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| AOI | Areas of Interest |
| FDR | False Discovery Rate |
| GLMM | Generalized Linear Mixed-Effects Model |
| HT | Human Translation |
| L1 | First Language |
| L2 | Second Language |
| LL | Log-Likelihood |
| LM | Language Model |
| LLM | Large Language Model |
| LMM | Linear Mixed-Effects Model |
| NMT | Neural Machine Translation |
| PE | Post-Editing |
Appendix A. Predictor Definitions and Feature Glossary
Table A1.
Surprisal predictors used in the analysis.
Table A2.
Encoder self-attention predictors.
Table A3.
Cross-attention predictors.
Table A4.
Decoder self-attention predictors.
Appendix A.1. Features Derived from Encoder Self-Attention
Let denote encoder attention from source token u to source position i, and let be source EOS.
Appendix A.2. Features Derived from Cross-Attention
Let denote cross-attention from target token v to source position i; the subscript y indicates summation over the full target sequence .
Appendix A.3. Features Derived from Decoder Self-Attention
Let denote decoder self-attention from target token v to target position j.
Appendix B. Random-Effects Structure Selection
Every comparison began from the correlated maximal structure and was simplified only when the model failed to converge or was singular. Table A5 reports the structure ultimately fitted in each model family. Across the 666 main-effect and residual attention comparisons, 341 (51%) retained a maximal structure (256 correlated, 85 uncorrelated), 78 used by-participant slopes, and 247 reached the random-intercept floor. The floor was reached almost entirely by the sparse duration and post-editing subsets, where slope variances could not be estimated. Of these 247 comparisons, 81 had a near-zero (boundary) variance estimate; their fixed-effect estimates were stable, and the corresponding effects were interpreted cautiously.
Table A5.
Final random-effects structure across model families, after the maximal-to-reduced recovery ladder. Counts are numbers of base/augmented comparisons.
Appendix C. Task Materials
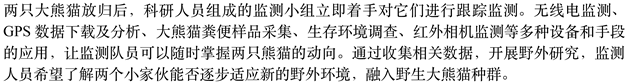
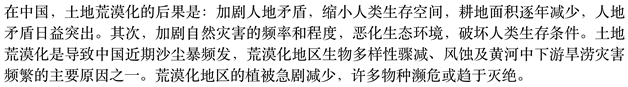
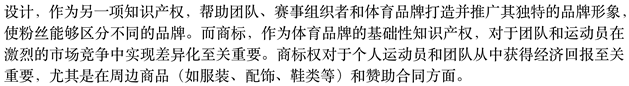
This appendix provides the source texts used in all four task conditions and the drafts supplied in the post-editing conditions.
Appendix C.1. Source Texts
- Text T1 (English)
The problem is, while several tools seem to be gaining ground in computer models, laboratories, and even real-world experiments, public discussion has not kept pace with their advancement. To date, there has been too little transparency and international dialog around the progress, feasibility, risks, and benefits of these efforts. Climate engineering and current mitigation and adaptation efforts are not mutually exclusive. Experts generally agree that these new technological approaches alone are unlikely to provide adequate protection from the dangers posed by rising global temperatures.
- Text T2 (Chinese)
- Text P1 (English)
Design, another IP right, enables teams, organizers of sporting competitions and sports brands to develop and promote their unique and distinct identity and for fans to distinguish between them. And trademarks, which underpin sports branding, are an exceptionally important IP right for teams and athletes to differentiate themselves and stand apart in a highly competitive market. Trademark rights are critical in allowing individuals players and teams to gain a monetary reward from, for example, merchandising-including apparel, accessories, footwear and more-and sponsorship deals.
- Text P2 (Chinese)
Appendix C.2. Drafts for Post-Editing
- Draft P1 (Chinese)
- Draft P2 (English)
In China, the consequences of land desertification are profound: it intensifies the conflict between humans and land, reduces living space for humans, and causes a continuous decline in arable land. This exacerbates the growing imbalance between human needs and the land’s capacity to support them. Furthermore, it increases the frequency and severity of natural disasters, worsens the ecological environment, and threatens human survival conditions. Desertification is one of the primary causes of the recent surge in sandstorms across China, the rapid loss of biodiversity in desertified regions, and the frequent drought and flood disasters along the middle and lower reaches of the Yellow River. In desertified areas, vegetation is drastically reduced, and many species are either endangered or on the verge of extinction.
References
- Rayner, K. Eye movements in reading and information processing: 20 years of research. Psychol. Bull. 1998, 124, 372–422. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Reichle, E.D. Computational models of reading: A primer. Lang. Linguist. Compass 2015, 9, 271–284. [Google Scholar] [CrossRef] [Scilit]
- Clifton, C., Jr.; Staub, A.; Rayner, K. Eye movements in reading words and sentences. In Eye Movements: A Window on Mind and Brain; van Gompel, R.P.G., Fischer, M.H., Murray, W.S., Hill, R.L., Eds.; Elsevier: Amsterdam, The Netherlands, 2007; pp. 341–371. [Google Scholar] [CrossRef] [Scilit]
- Macizo, P.; Bajo, M.T. Reading for repetition and reading for translation: Do they involve the same processes? Cognition 2006, 99, 1–34. [Google Scholar] [CrossRef] [Scilit]
- Balling, L.W.; Hvelplund, K.T.; Sjørup, A.C. Evidence of parallel processing during translation. Meta 2014, 59, 234–259. [Google Scholar] [CrossRef] [Scilit]
- Carl, M.; Schaeffer, M.; Bangalore, S. The CRITT translation process research database. In New Directions in Empirical Translation Process Research; Carl, M., Bangalore, S., Schaeffer, M., Eds.; Springer: Cham, Switzerland, 2016; pp. 13–54. [Google Scholar] [CrossRef] [Scilit]
- Schaeffer, M.; Carl, M. Measuring the cognitive effort of literal translation processes. In Proceedings of the EACL 2014 Workshop on Humans and Computer-Assisted Translation, Gothenburg, Sweden, 26 April 2014; pp. 29–37. [Google Scholar] [CrossRef] [Scilit]
- Carl, M.; Toledo Baez, M.C. Machine translation errors and the translation process: A study across different languages. J. Spec. Transl. 2019, 31, 107–132. [Google Scholar] [CrossRef] [Scilit]
- Nitzke, J. Problem Solving Activities in Post-Editing and Translation from Scratch: A Multi-Method Study; Language Science Press: Berlin, Germany, 2019. [Google Scholar] [CrossRef]
- Carl, M.; Schaeffer, M.J. Why translation is difficult: A corpus-based study of non-literality in post-editing and from-scratch translation. Hermes 2017, 56, 43–57. [Google Scholar] [CrossRef] [Scilit]
- Wei, Y. Entropy as a measurement of cognitive load in translation. In Proceedings of the 15th Biennial Conference of the Association for Machine Translation in the Americas, Orlando, FL, USA, 12–16 September 2022; Workshop 1: Empirical Translation Process Research. pp. 75–86. [Google Scholar]
- Lim, Z.W.; Cohn, T.; Kemp, C.; Vylomova, E. Predicting human translation difficulty using automatic word alignment. In Findings of the Association for Computational Linguistics: ACL 2023; Association for Computational Linguistics: Toronto, ON, Canada, 2023; pp. 11590–11601. [Google Scholar] [CrossRef] [Scilit]
- Lim, Z.W.; Vylomova, E.; Kemp, C.; Cohn, T. Predicting human translation difficulty with neural machine translation. Trans. Assoc. Comput. Linguist. 2024, 12, 1479–1496. [Google Scholar] [CrossRef] [Scilit]
- Hale, J. A probabilistic Earley parser as a psycholinguistic model. In Proceedings of the Second Meeting of the North American Chapter of the Association for Computational Linguistics on Language Technologies, Pittsburgh, PA, USA, 2–7 June 2001. [Google Scholar] [CrossRef] [Scilit]
- Levy, R. Expectation-based syntactic comprehension. Cognition 2008, 106, 1126–1177. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Reichle, E.D. Computational Models of Reading: A Handbook; Oxford University Press: New York, NY, USA, 2021. [Google Scholar] [CrossRef] [Scilit]
- Rayner, K. Eye movements and attention in reading, scene perception, and visual search. Q. J. Exp. Psychol. 2009, 62, 1457–1506. [Google Scholar] [CrossRef] [Scilit]
- Kaakinen, J.K.; Hyönä, J. Task effects on eye movements during reading. J. Exp. Psychol. Learn. Mem. Cogn. 2010, 36, 1561–1566. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Strukelj, A.; Niehorster, D.C. One page of text: Eye movements during regular and thorough reading, skimming, and spell checking. J. Eye Mov. Res. 2018, 11, 1–22. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Cop, U.; Drieghe, D.; Duyck, W. Eye movement patterns in natural reading: A comparison of monolingual and bilingual reading of a novel. PLoS ONE 2015, 10, e0134008. [Google Scholar] [CrossRef] [Scilit]
- Duyck, W.; Van Assche, E.; Drieghe, D.; Hartsuiker, R.J. Visual word recognition by bilinguals in a sentence context: Evidence for nonselective lexical access. J. Exp. Psychol. Learn. Mem. Cogn. 2007, 33, 663–679. [Google Scholar] [CrossRef] [Scilit]
- Hoversten, L.J.; Martin, C.D. Parafoveal processing in bilingual readers: Semantic access within but not across languages. J. Exp. Psychol. Hum. Percept. Perform. 2023, 49, 1466–1483. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Deilen, S.; Lapshinova-Koltunski, E.; Carl, M. Cognitive aspects of compound translation: Insights into the relation between implicitation and cognitive effort from a translation process perspective. Ampersand 2023, 11, 100156. [Google Scholar] [CrossRef] [Scilit]
- Wang, Y.; Li, S.; Rasmussen, Y.Z. Translators’ allocation of cognitive resources in two translation directions: A study using eye-tracking and keystroke logging. Appl. Sci. 2025, 15, 4401. [Google Scholar] [CrossRef] [Scilit]
- Chen, S.; Feng, J.; Carl, M. Exploring preparatory reading in bidirectional sight and written translation through clustering analysis of eye-tracking data. PLoS ONE 2025, 20, e0329858. [Google Scholar] [CrossRef] [Scilit]
- Monsalve, I.F.; Frank, S.L.; Vigliocco, G. Lexical surprisal as a general predictor of reading time. In Proceedings of the 13th Conference of the European Chapter of the Association for Computational Linguistics, Avignon, France, 23–27 April 2012; pp. 398–408. [Google Scholar]
- Smith, N.J.; Levy, R. The effect of word predictability on reading time is logarithmic. Cognition 2013, 128, 302–319. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Shain, C.; Meister, C.; Pimentel, T.; Cotterell, R.; Levy, R. Large-scale evidence for logarithmic effects of word predictability on reading time. Proc. Natl. Acad. Sci. USA 2024, 121, e2307876121. [Google Scholar] [CrossRef] [Scilit]
- Wilcox, E.G.; Pimentel, T.; Meister, C.; Cotterell, R.; Levy, R.P. Testing the predictions of surprisal theory in 11 languages. Trans. Assoc. Comput. Linguist. 2023, 11, 1451–1470. [Google Scholar] [CrossRef] [Scilit]
- Frank, S.L.; Bod, R. Insensitivity of the human sentence-processing system to hierarchical structure. Psychol. Sci. 2011, 22, 829–834. [Google Scholar] [CrossRef] [Scilit]
- Goodkind, A.; Bicknell, K. Predictive power of word surprisal for reading times is a linear function of language model quality. In Proceedings of the 8th Workshop on Cognitive Modeling and Computational Linguistics (CMCL 2018), Salt Lake City, UT, USA, 7 January 2018; pp. 10–18. [Google Scholar] [CrossRef] [Scilit]
- Kuribayashi, T.; Oseki, Y.; Ito, T.; Yoshida, R.; Asahara, M.; Inui, K. Lower perplexity is not always human-like. In Proceedings of the ACL-IJCNLP 2021 (Volume 1: Long Papers), Online, 1–6 August 2021; pp. 5203–5217. [Google Scholar] [CrossRef] [Scilit]
- Oh, B.-D.; Schuler, W. Transformer-based language model surprisal predicts human reading times best with about two billion training tokens. In Proceedings of the Findings of the Association for Computational Linguistics: EMNLP 2023, Singapore, 6–10 December 2023; pp. 1915–1921. [Google Scholar] [CrossRef] [Scilit]
- Škrjanec, I.; Demberg, V. Language models that match reader experience are better predictors of reading times. J. Mem. Lang. 2026, 146, 104677. [Google Scholar] [CrossRef] [Scilit]
- Chen, L.; Oralova, G.; Fang, X.; Clark, S.; Teodorescu, D.; Helfrich, M.; Fyshe, A.; Demmans Epp, C.; Perfetti, C. Text difficulty modulates the surprisal effect in self-paced reading. Read. Writ. 2026. advance online publication. [Google Scholar] [CrossRef] [Scilit]
- Kuribayashi, T.; Oseki, Y.; Ben Taieb, S.; Inui, K.; Baldwin, T. Large language models are human-like internally. Trans. Assoc. Comput. Linguist. 2025, 13, 1743–1766. [Google Scholar] [CrossRef] [Scilit]
- Kuribayashi, T.; Warstadt, A.; Oseki, Y.; Wilcox, E. Dual alignment between language model layers and human sentence processing. arXiv 2026, arXiv:2604.18563. [Google Scholar] [CrossRef] [Scilit]
- Wang, S.-F.; Prévot, L.; Chi, J.-A.; Huang, R.-S.; Hsieh, S.-K. Spontaneous speech variables for evaluating LLMs cognitive plausibility. arXiv 2025, arXiv:2505.16277. [Google Scholar] [CrossRef] [Scilit]
- Clark, T.H.; Arriaga, C.; Conde, J.; Martínez, G.; Reviriego, P. To words and beyond: Probing large language models for sentence-level psycholinguistic norms of memorability and reading times. arXiv 2026, arXiv:2603.12105. [Google Scholar] [CrossRef] [Scilit]
- Costa-jussa, M.R.; Cross, J.; Çelebi, O.; Elbayad, M.; Heafield, K.; Heffernan, K.; Kalbassi, E.; Lam, J.; Licht, D.; Maillard, J.; et al. No language left behind: Scaling human-centered machine translation. arXiv 2022, arXiv:2207.04672. [Google Scholar] [CrossRef] [Scilit]
- Oh, B.-D.; Schuler, W. Entropy-and distance-based predictors from GPT-2 attention patterns predict reading times over and above GPT-2 surprisal. In Proceedings of the 2022 Conference on Empirical Methods in Natural Language Processing, Abu Dhabi, United Arab Emirates, 7–11 December 2022; pp. 9324–9334. [Google Scholar] [CrossRef] [Scilit]
- Ryu, S.H.; Lewis, R.L. Accounting for agreement phenomena in sentence comprehension with transformer language models: Effects of similarity-based interference on surprisal and attention. In Proceedings of the Workshop on Cognitive Modeling and Computational Linguistics, Online, 10 June 2021; pp. 61–71. [Google Scholar] [CrossRef] [Scilit]
- Ferrando, J.; Costa-jussa, M.R. Attention weights in transformer NMT fail aligning words between sequences but largely explain model predictions. In Proceedings of the Findings of the Association for Computational Linguistics: EMNLP 2021, Virtual, 9 November 2021; pp. 434–443. [Google Scholar] [CrossRef] [Scilit]
- Opedal, A.; Chodroff, E.; Cotterell, R.; Wilcox, E.G. On the role of context in reading time prediction. arXiv 2024, arXiv:2409.08160. [Google Scholar] [CrossRef] [Scilit]
- OpenAI; Hurst, A.; Lerer, A.; Goucher, A.; Perelman, A.; Brundage, M.; Epstein, A.; McGrew, B. GPT-4o system card. arXiv 2024, arXiv:2410.21276. [Google Scholar] [CrossRef] [Scilit]
- Carl, M. Translog-II: A program for recording user activity data for empirical reading and writing research. In Proceedings of the Eighth International Conference on Language Resources and Evaluation (LREC’12), Istanbul, Turkey, 21–27 May 2012; pp. 4108–4112. [Google Scholar]
- Zhao, H.; Gu, X. China Accreditation Test for Translators and Interpreters (CATTI): Test review based on the language pairing of English and Chinese. Lang. Test. 2016, 33, 439–446. (In Chinese) [Google Scholar] [CrossRef] [Scilit]
- Xu, Y.; Liu, Y. Investigating the content validity of practical translation test in CATTI Level II. Transl. Res. Teach. 2022, 2, 120–129. [Google Scholar]
- Tseng, A. mDeBERTa-V3-Base-Readability: A Fine-Tuned Multilingual DeBERTa Model for Cross-Lingual Readability Assessment; Hugging Face, 2024. Available online: https://huggingface.co/agentlans/mdeberta-v3-base-readability (accessed on 1 December 2025).
- Carl, M. Translation norms, translation behavior, and continuous vector space models. In Explorations in Empirical Translation Process Research; Carl, M., Ed.; Springer: Cham, Switzerland, 2021; pp. 357–388. [Google Scholar] [CrossRef] [Scilit]
- Shliazhko, O.; Fenogenova, A.; Tikhonova, M.; Mikhailov, V.; Evlampiev, A.; Artemova, E. mGPT: Few-shot learners go multilingual. Trans. Assoc. Comput. Linguist. 2024, 12, 58–75. [Google Scholar] [CrossRef] [Scilit]
- Devlin, J.; Chang, M.-W.; Lee, K.; Toutanova, K. BERT: Pre-training of deep bidirectional transformers for language understanding. In Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Minneapolis, MN, USA, 2–7 June 2019; Volume 1 (Long and Short Papers). pp. 4171–4186. [Google Scholar] [CrossRef] [Scilit]
- Wang, A.; Cho, K. BERT has a mouth, and it must speak: BERT as a Markov random field language model. In Proceedings of the Workshop on Methods for Optimizing and Evaluating Neural Language Generation, Minneapolis, MN, USA, 2–7 June 2019; pp. 30–36. [Google Scholar] [CrossRef] [Scilit]
- Salazar, J.; Liang, D.; Nguyen, T.Q.; Kirchhoff, K. Masked language model scoring. Trans. Assoc. Comput. Linguist. 2020, 8, 421–436. [Google Scholar] [CrossRef] [Scilit]
- Barr, D.J.; Levy, R.; Scheepers, C.; Tily, H.J. Random effects structure for confirmatory hypothesis testing: Keep it maximal. J. Mem. Lang. 2013, 68, 255–278. [Google Scholar] [CrossRef] [Scilit]
- Benjamini, Y.; Hochberg, Y. Controlling the false discovery rate: A practical and powerful approach to multiple testing. J. R. Stat. Soc. Ser. B Methodol. 1995, 57, 289–300. [Google Scholar] [CrossRef] [Scilit]
- R Core Team. R: A Language and Environment for Statistical Computing; R Foundation for Statistical Computing: Vienna, Austria, 2026; Available online: https://www.r-project.org/ (accessed on 1 December 2025).
- Bates, D.; Mächler, M.; Bolker, B.; Walker, S. Fitting linear mixed-effects models using lme4. J. Stat. Softw. 2015, 67, 1–48. [Google Scholar] [CrossRef] [Scilit]
- Olsen, M.K.; Schafer, J.L. A two-part random-effects model for semicontinuous longitudinal data. J. Am. Stat. Assoc. 2001, 96, 730–745. [Google Scholar] [CrossRef] [Scilit]
- Dijkstra, T.; van Heuven, W.J.B. The architecture of the bilingual word recognition system: From identification to decision. Bilingualism 2002, 5, 175–197. [Google Scholar] [CrossRef] [Scilit]
- Ruiz, C.; Paredes, N.; Macizo, P.; Bajo, M.T. Activation of lexical and syntactic target language properties in translation. Acta Psychol. 2008, 128, 490–500. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Cop, U.; Keuleers, E.; Drieghe, D.; Duyck, W. Frequency effects in monolingual and bilingual natural reading. Psychon. Bull. Rev. 2015, 22, 1216–1234. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Vieira, L.N. How do measures of cognitive effort relate to each other? A multivariate analysis of post-editing process data. Mach. Transl. 2016, 30, 41–62. [Google Scholar] [CrossRef] [Scilit]
- Daems, J.; Vandepitte, S.; Hartsuiker, R.J.; Macken, L. Identifying the machine translation error types with the greatest impact on post-editing effort. Front. Psychol. 2017, 8, 1282. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Koponen, M.; Salmi, L.; Nikulin, M. A product and process analysis of post-editor corrections on neural, statistical and rule-based machine translation output. Mach. Transl. 2019, 33, 61–90. [Google Scholar] [CrossRef] [Scilit]
- Jain, S.; Wallace, B.C. Attention is not explanation. In Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Minneapolis, MN, USA, 2–7 June 2019; Volume 1 (Long and Short Papers). pp. 3543–3556. [Google Scholar] [CrossRef] [Scilit]
- Serrano, S.; Smith, N.A. Is attention interpretable? In Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics, Florence, Italy, 28 July–2 August 2019; pp. 2931–2951. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.