


Abstract
In recent decades, data collection technologies have evolved to facilitate the monitoring and improvement of numerous activities and processes in everyday human life. Their evolution is propelled by the advancement of artificial intelligence (AI), which aims to emulate human intelligence in the execution of related tasks. The remarkable success of deep learning (DL) and computer vision (CV) on image data prompted researchers to consider its application to time series and multivariate data. In this context, time series imaging has been identified as the research field for the transformation of time series data (a one-dimensional data format) into images (a two-dimensional data format). These data can be the variables or features of a system or phenomenon under consideration. State-of-the-art techniques for time series imaging include recurrence plot (RP), Gramian angular field (GAF), and Markov transition field (MTF). This paper proposes a novel, robust, and simple technique of time series imaging using Grayscale Fingerprint Features Field Imaging (G3FI). This novel technique is distinguished by the low resolution of the resulting image and the simplicity of the transformation procedure. The efficacy of the novel and state-of-the-art techniques for enhancing the performance of CNN-based classification models on time series datasets is thoroughly examined and compared.
1. Introduction
Smart data and information collection technologies and their processing techniques have undergone enormous and unprecedented advances. These technologies include the Internet of Things (IoT), cell phones, GPS, Bluetooth, and smart cards, especially in hard-to-reach areas, and their integration is becoming easier and more popular in human daily life and related activities, such as in industry, healthcare, finance, and other fields [1,2,3]. The intelligent collection of these data is typically executed over specific, time-ordered intervals. For this reason, these data are generally referred to as time series data [4]. This enormous growth is usually accompanied by the increasing availability of data. Some of the collected, created, or generated data are strongly related to the specific task space (informative), while other data could be redundant (non-informative) in terms of the desired task performance. Consequently, this phenomenon results in a diminution of storage capacity and escalation in the computing time of the corresponding processing operations due to non-informative data. Therefore, it is necessary to define the valuable and informative data among the collected raw data in order to reduce the associated high-cost storage and computing time of the operations [1,2,4]. Extracting actionable information from the raw data collected and processing and analyzing them leads to a wide range of tasks such as current state representation, future state prediction, automation opportunity detection, anomaly detection, predictive maintenance, condition monitoring, cybersecurity, and human activity recognition [2,3].
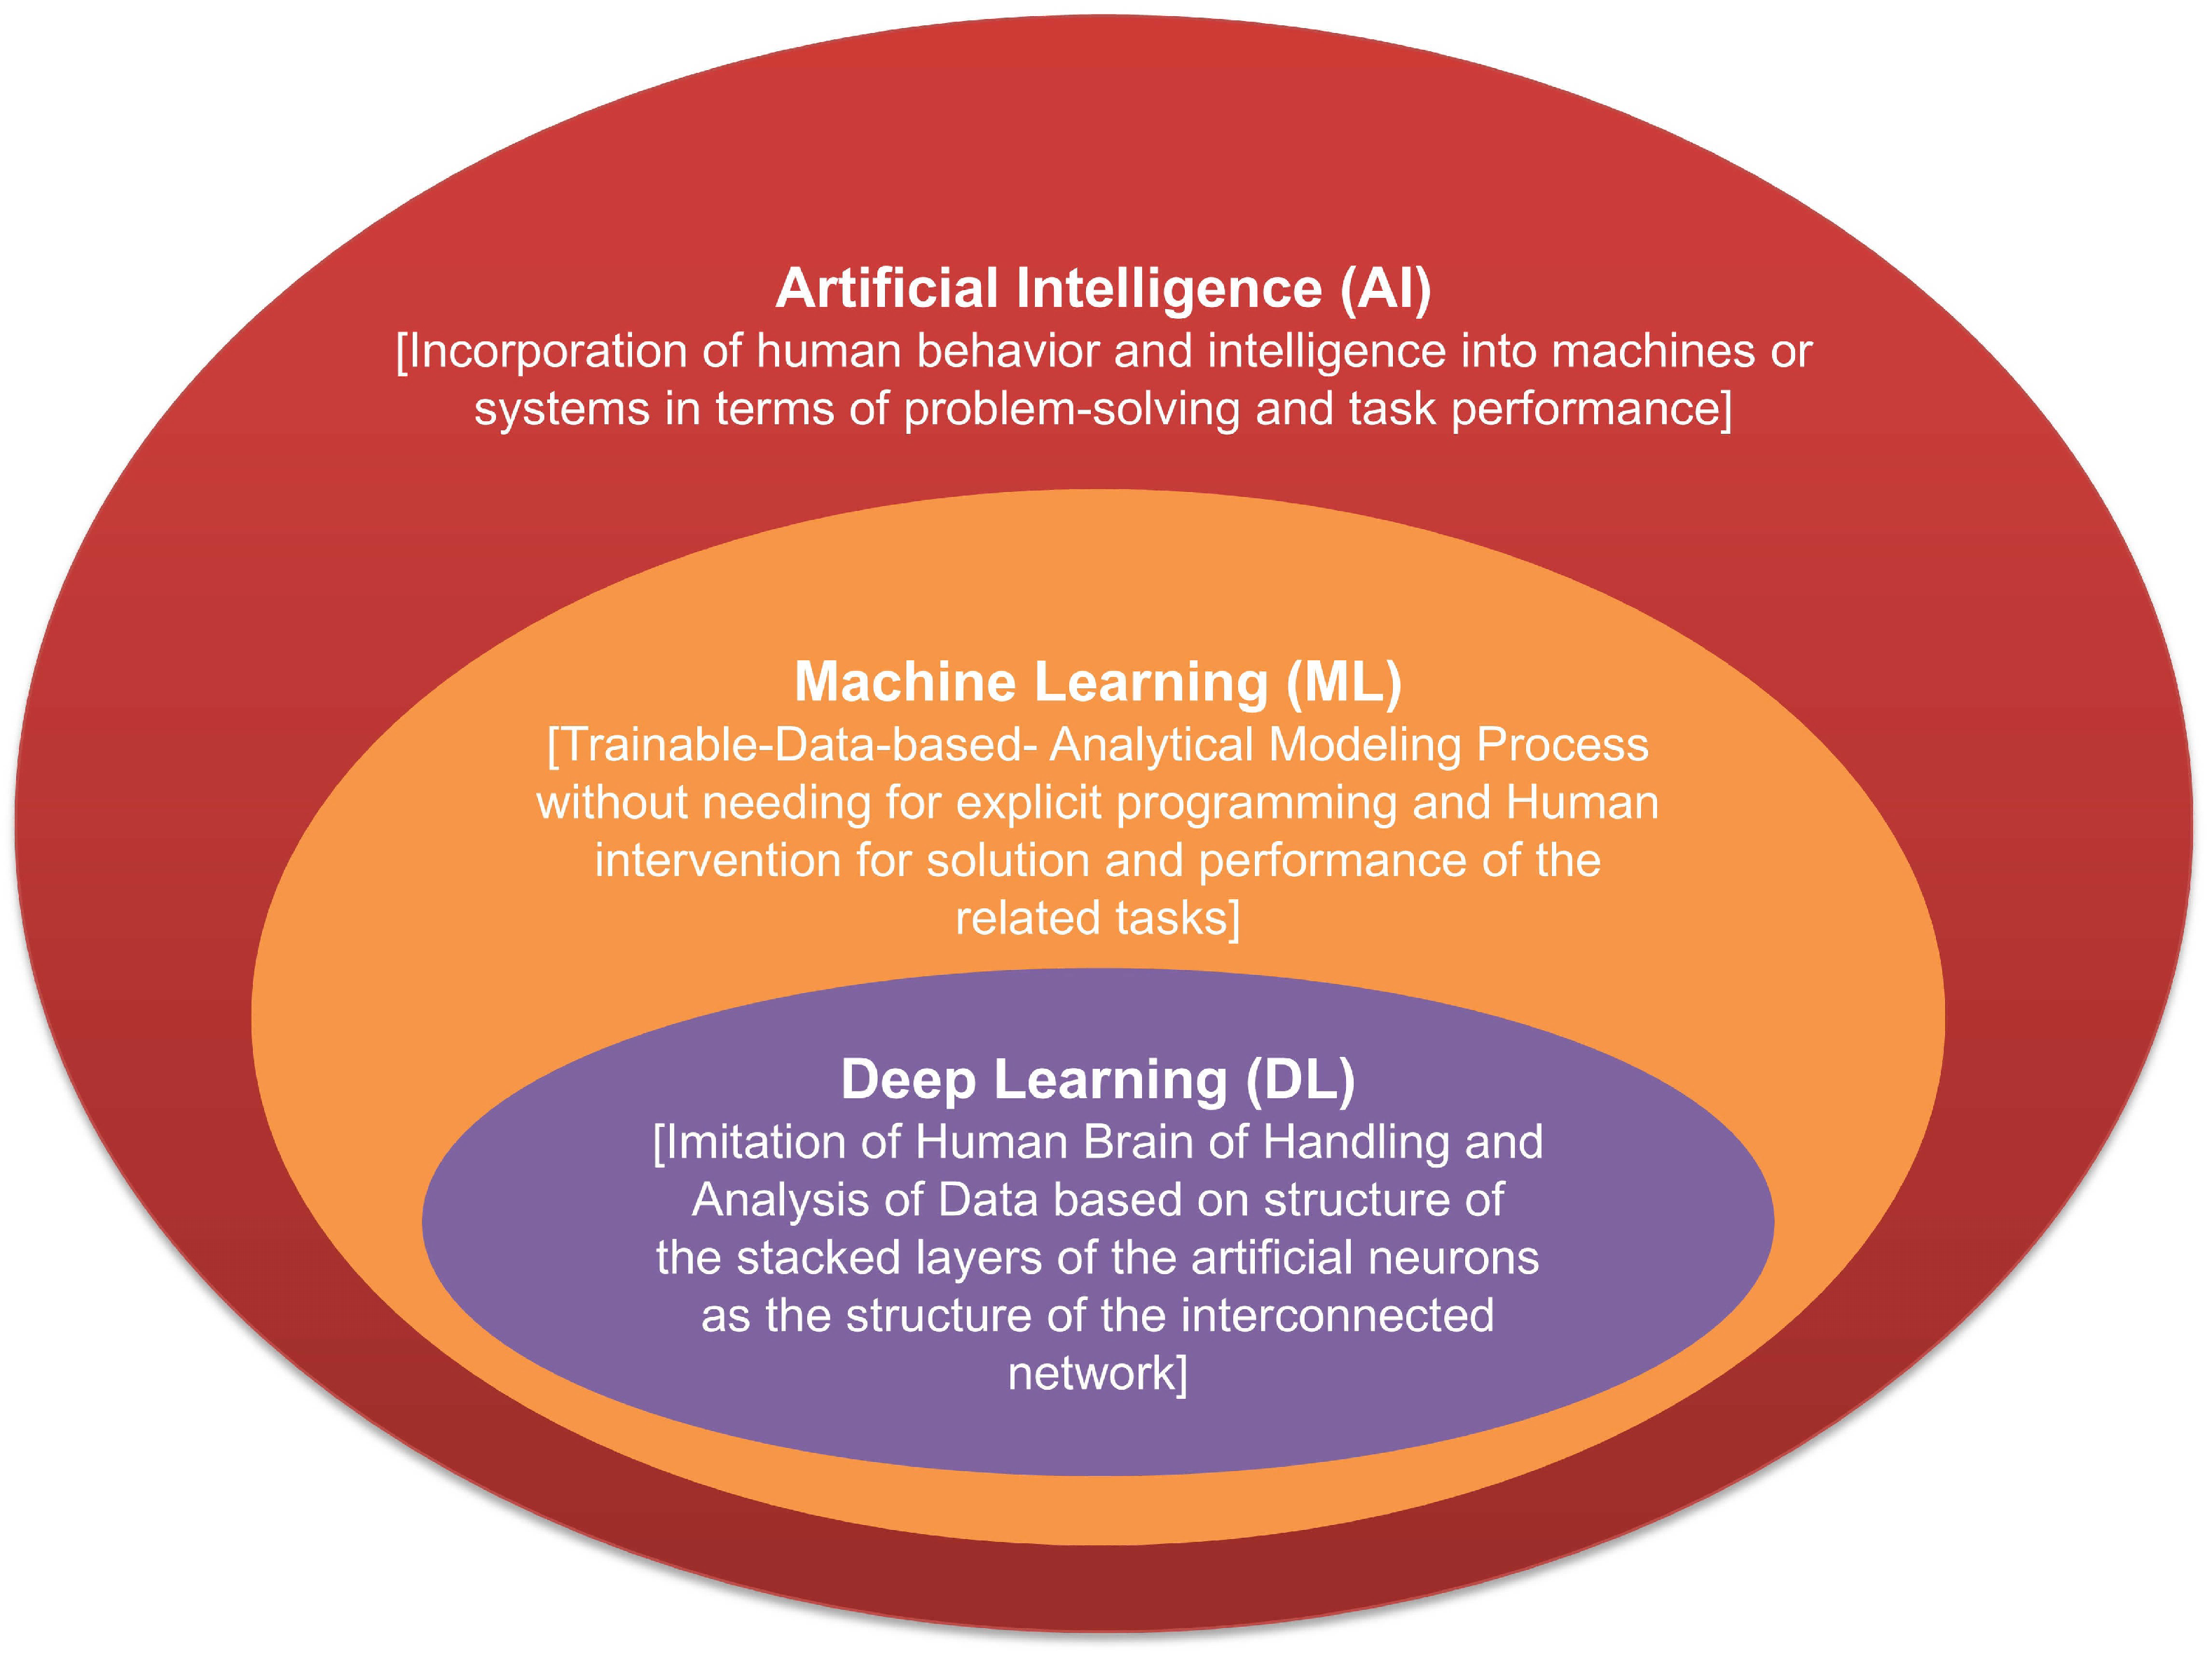
Analysis of time series data for the purpose of obtaining this useful information can be categorized as either conventional or data-driven [1,2]. Statistical models such as exponential smoothing and ARIMA, as examples of conventional models, can be modified by “non-data hungry” and computationally cheap approaches. However, they (1) have low generalization ability to prescribe the data generation process of the series, (2) show limited learning ability, and (3) are usually unable to extract the valuable information hidden in the large datasets. Addressing the tasks associated with analyzing time series data as the data increase requires the application of scalable, robust, and efficient processing and analysis tools. These requirements cannot be met using conventional methods. Therefore, AI-based models are strongly recommended for these purposes. Due to the specifications (e.g., the modeling of nonlinear relationships, automatic pattern recognition, scalability) of AI-based models, these models are better suited and more efficient than conventional models (statistical, signal processing, etc.) to perform tasks related to the large data amounts [1,2,4,5,6]. AI-based models incorporate machine learning (ML) and deep learning (DL), as illustrated in Figure 1, which also shows the parental relation among them [7].
Figure 1.
Position of ML and DL within the field of AI.
In general, ML models suffer from the following issues [8,9,10,11,12,13]:
- They require manual feature engineering.
- They are highly subjective.
- They do not generalize well in other scenarios.
- They require a high level of expertise.
- They are time-consuming during data preprocessing with more than 50% of the whole data processing.
- They are influenced by human factors.
To address these issues in relation to ML models, DL models have been introduced as a powerful framework with high generalizability, objectivity, performance, and integration of automated feature extraction and final classification processes in a single shot [14,15]. For example, the recurrent neural network (RNN) is one of many different DL structures; it has been shown to be powerful in modeling time series data [15,16]. Specifically, the long short-term memory (LSTM) structure has been shown to possess high learning capability for information within a time sequence far in the past [17].
Due to the increasing availability and complexity of time series sequences, RNN/LSTM models cannot learn from the information far in the past of these long sequences to achieve the most accurate modeling without loss of information. To solve this problem, the technique of “Imaging/Image-Encoded Time Series” is introduced to preserve all information, even in long sequences. With this novel technique, convolutional neural networks (CNN) achieve remarkable performances in computer vision (CV) and can be used to accomplish tasks related to time series prediction and classification [18,19,20,21,22].
2. Review of Related Work and Basic Methods
2.1. Definitions
The types of time series can be basically classified according to the number of descriptive variables/features measured/observed during the sampling period [23]:
- Univariate time series: only one descriptive variable/feature has been measured and observed over time.
- Multivariate time series: several descriptive variables/features have been measured and observed over time.
During the sampling time of the different descriptive characteristics of the considered process or phenomenon, the related multivariate time series dataset consists of many samples stored in a row, which represents the considered observation/measurement time, and the different descriptive features are stored in the columns for each sample. Therefore, the imaging time series can be defined as the mathematical process that transfers each sample of a multivariate time series, considered a vector of descriptive features, into a matrix format that can be considered a 2D image in the context of DL and CV systems [19,24].
2.2. Imaging Time Series Techniques
This section discusses state-of-the-art transformation techniques. These techniques include the recurrence plot, Gramian angular summation/difference field, and Markov transition field.
2.2.1. Recurrence Plot (RP)
The RP was developed by Eckmann et al. [25] to visualize state recurrence () in a 2D or 3D phase/state space. Phase/state spaces higher than 3D can only be visualized via projection onto 2D or 3D subspaces.
Ramirez-Amaro et al. [26] stated, “The recurrence plot analysis provides us a way to visualize and quantify the dynamical systems behavior over the time. The construction of a recurrence plot (RP) from a time series begins with the determination of the trajectory of the system through phase-space. Seven different measures are extracted from the RP. These measures are obtained from diagonal and vertical structures of the RP.”
The RP allows us to trace and study the trajectory of an m-dimensional phase space through a two-dimensional representation of its repetitions, where the trajectory of the repetition of a state () over time between the initial time (i) and the considered time (j) through the original m-dimensional phase space is mathematically projected onto a two-dimensional square matrix whose elements are
- Ones (recurrent state: ;
- Zeros (transient state: .
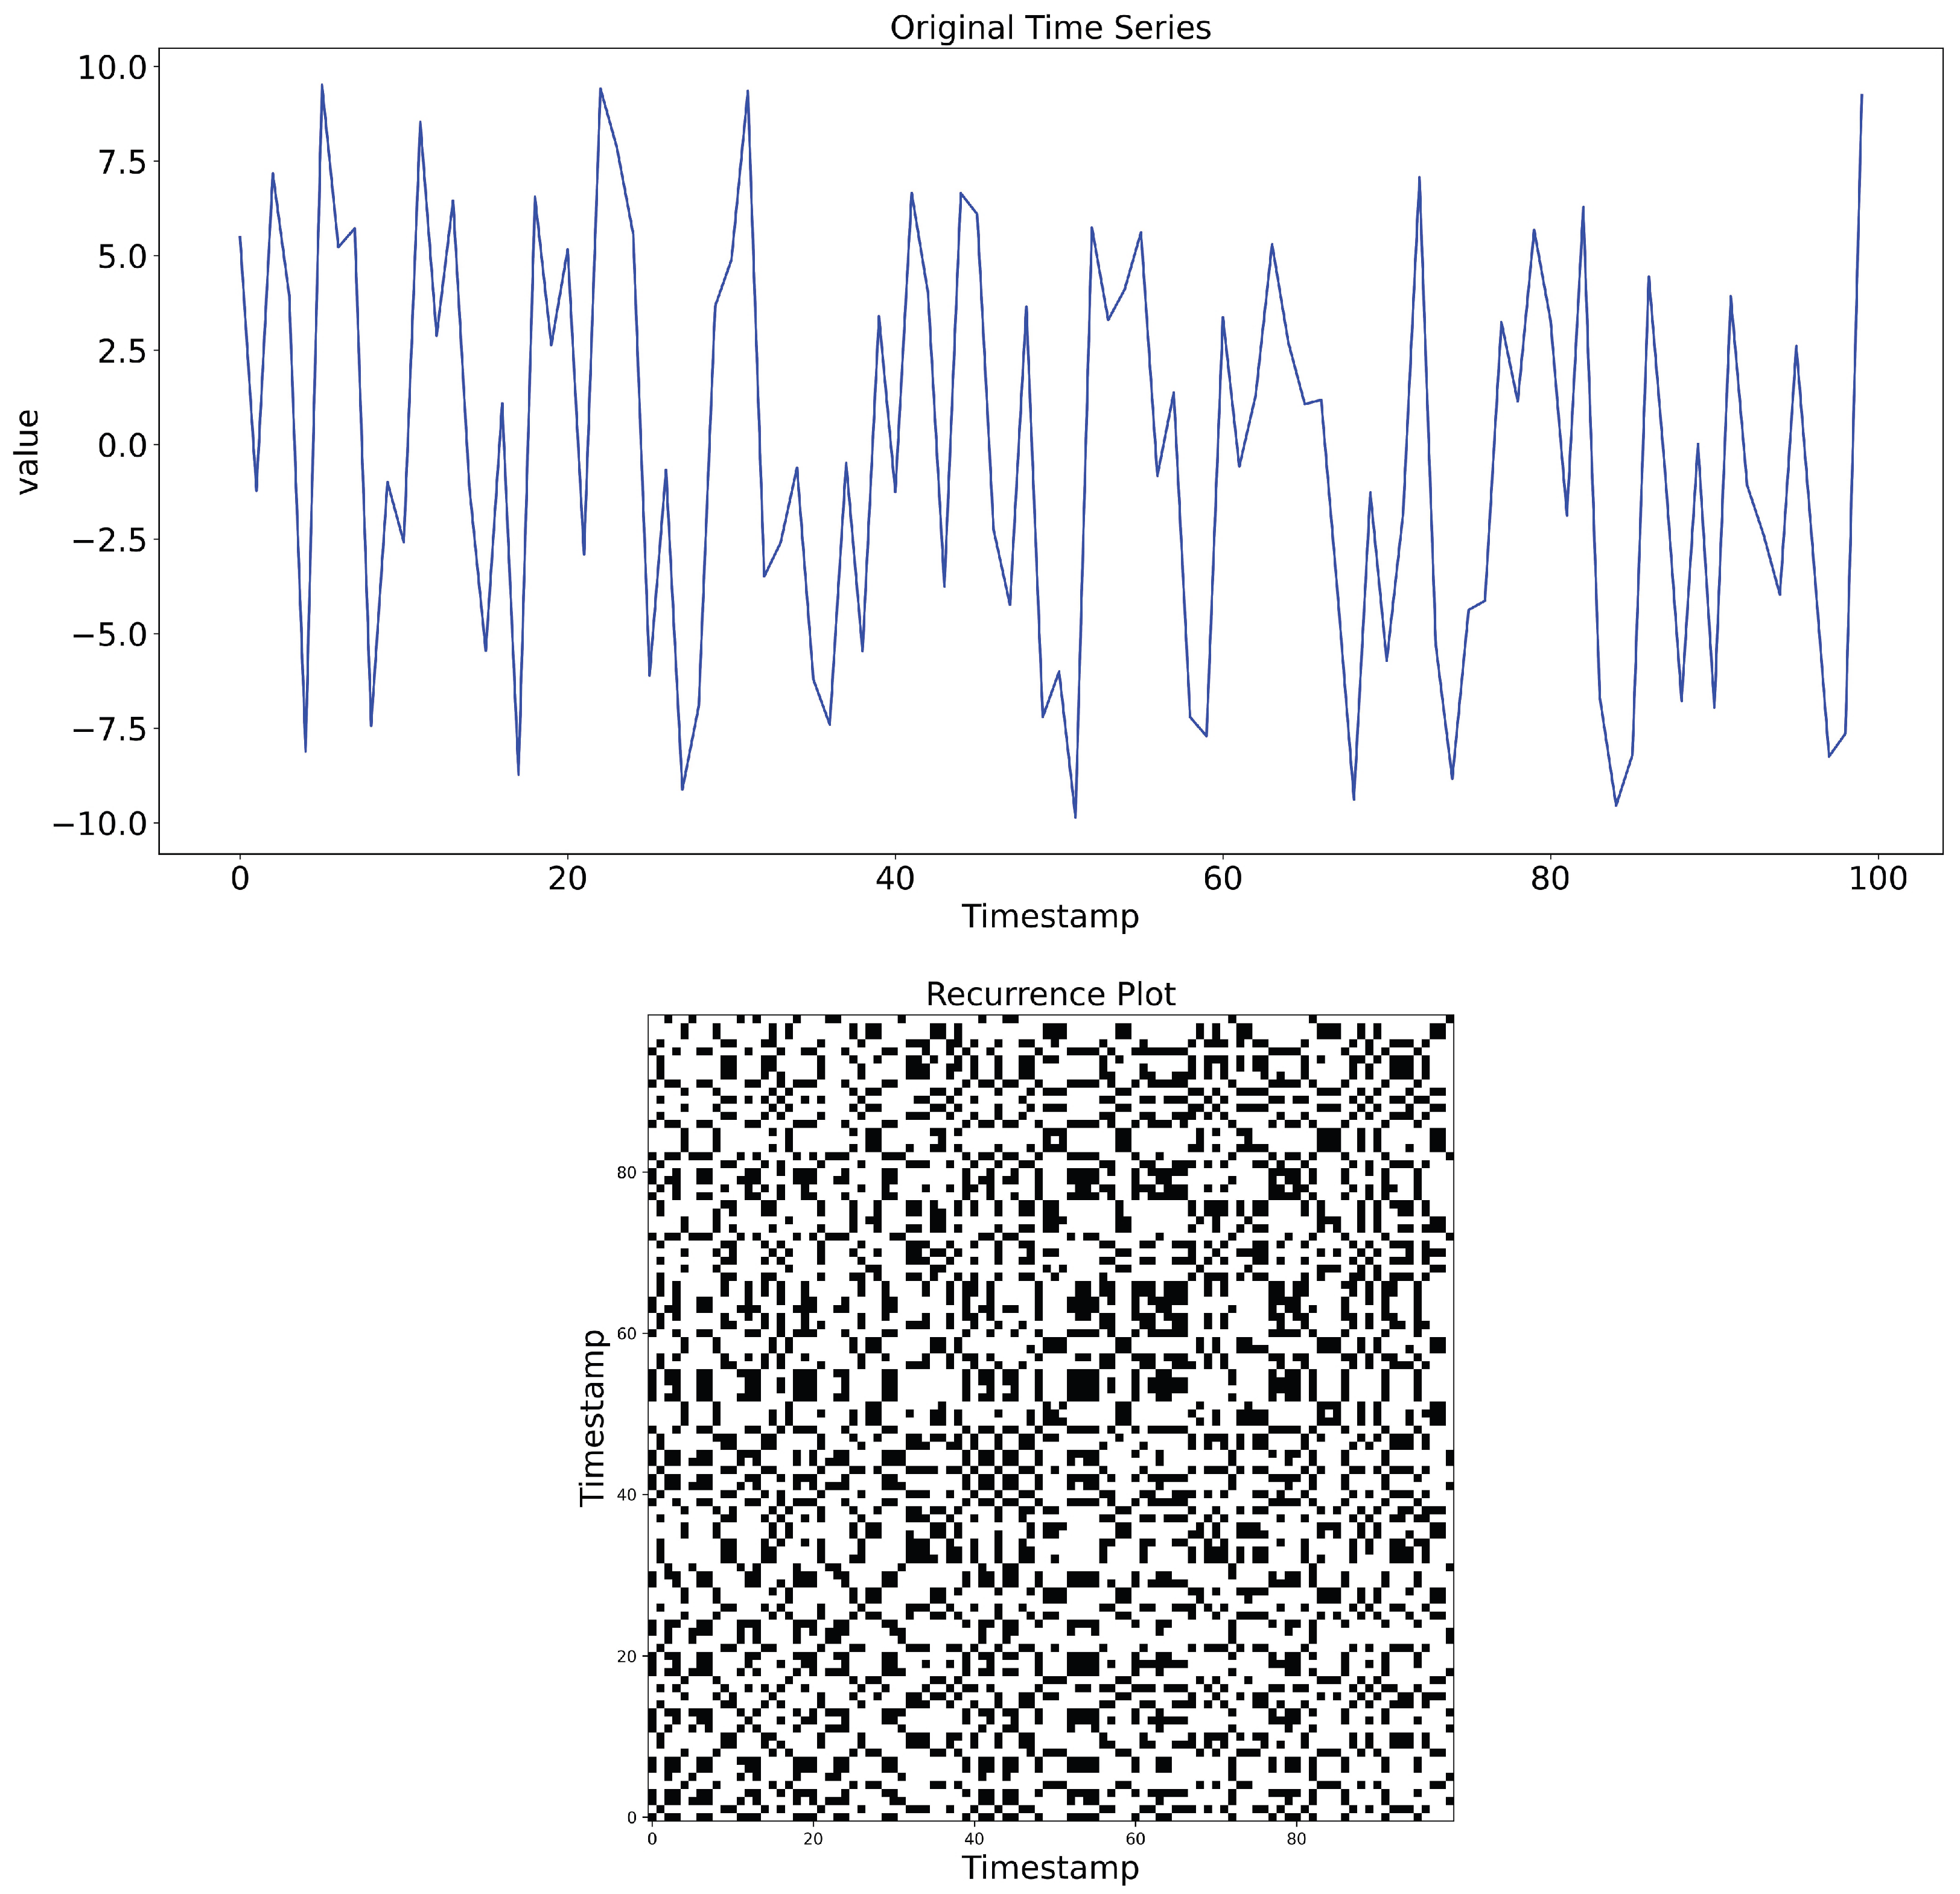
This matrix is represented graphically with black (recurrent state) and white (transient state) points, in the 2D time axis-based plot, as illustrated in Figure 2. Consequently, the RP aims to graphically display non-stationarity (changes in the related statistical properties over time) in time series.
In dynamical systems, a trajectory is defined as the set of points representing the future states resulting from a given initial state in the phase or state space [23,27]:
where
- m is the number of dimensions of the considered phase space.
- n is the length of the trajectory through the phase space/number of the future states resulting from a given initial state in phase space.
- is the time delay considered.
Figure 2.
Visualization of the recurrence of state () in a 2D or 3D phase/state space [28].
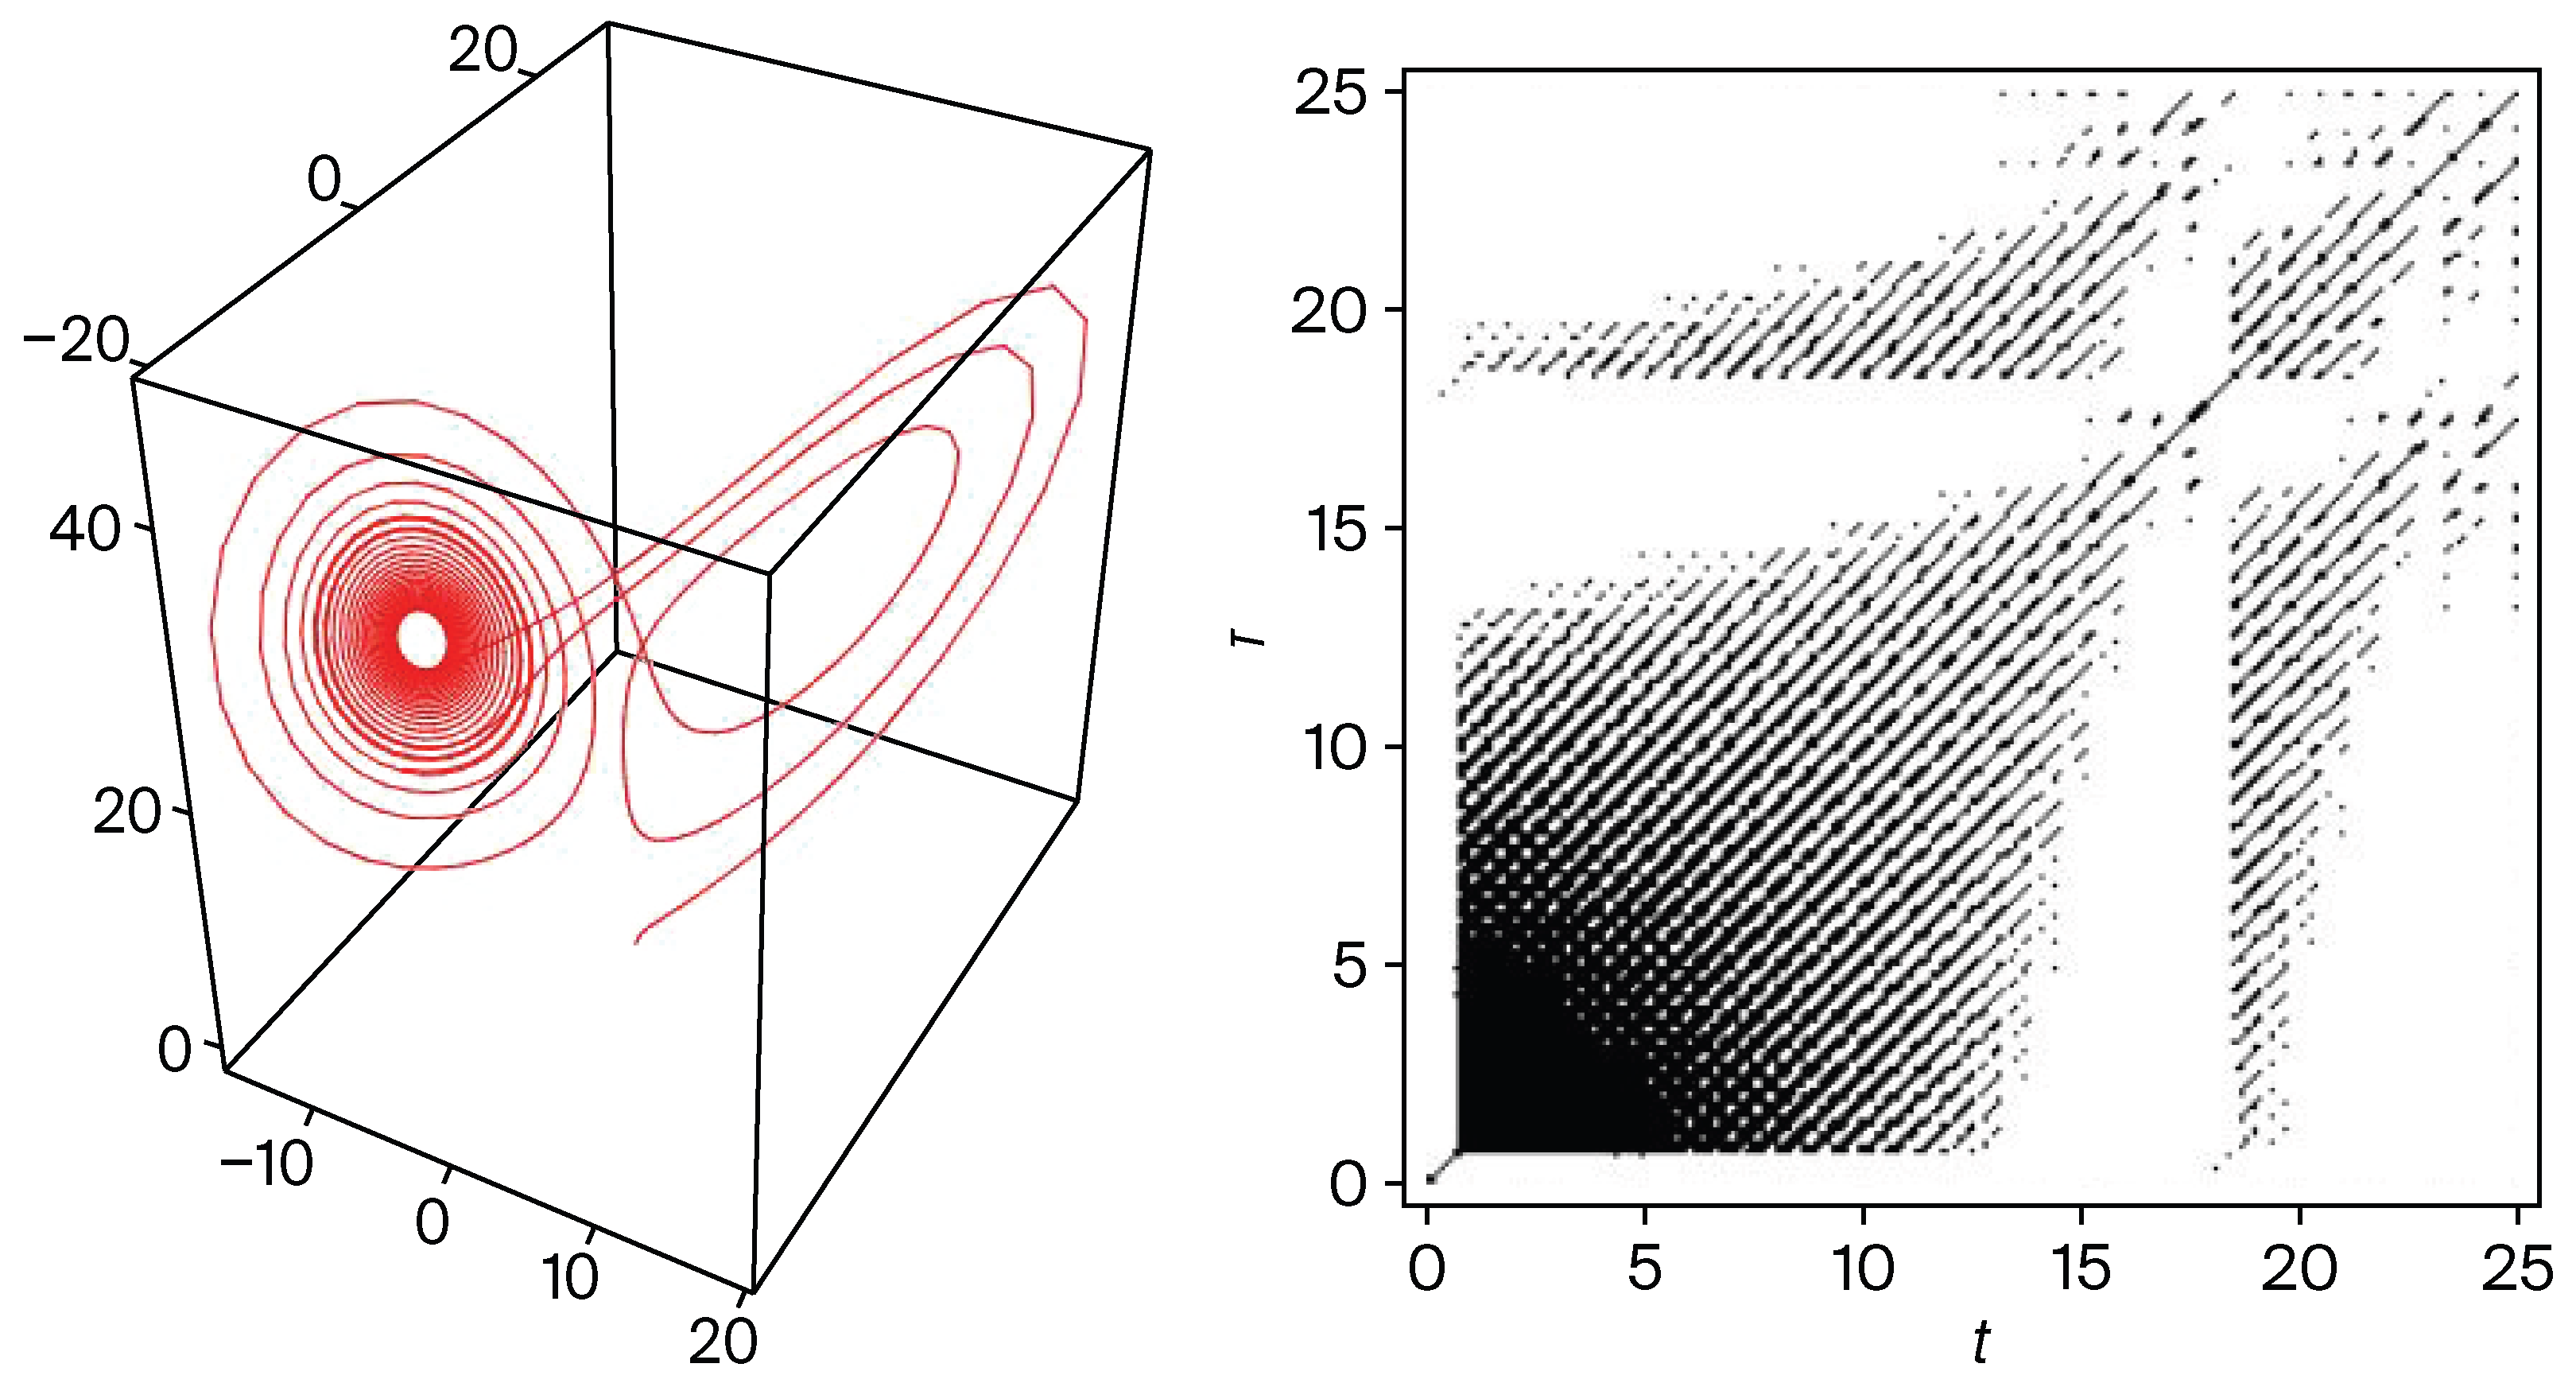
Therefore, the application of RP analysis as an imaging time series technique aims to extract the trajectories of the time series and then calculate the binarized pairwise distance matrix between them as a recurrence representation in the phase/state space. This matrix is denoted as R to build the recurrence diagram for the RP as follows [23,27]:
where
- is the binarized pairwise distance matrix of the trajectory of the recurrence of a state () between initial time point i and time point j over time in the m-dimensional phase space.
- is the Heaviside function.
- is the recurrence threshold.
- is the norm operator (the Euclidean norm is typically used).
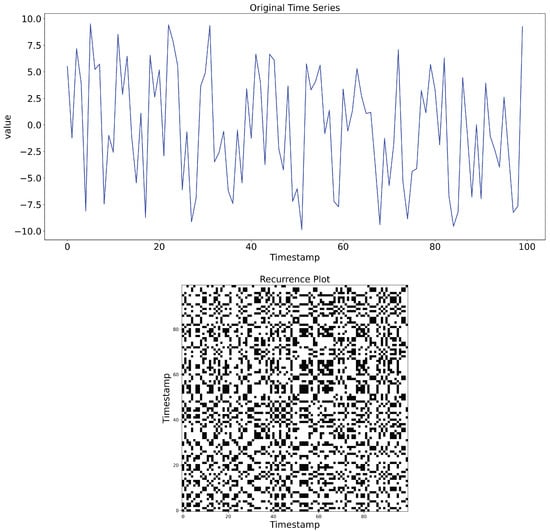
Figure 3.
Example 1 of RP of time series.
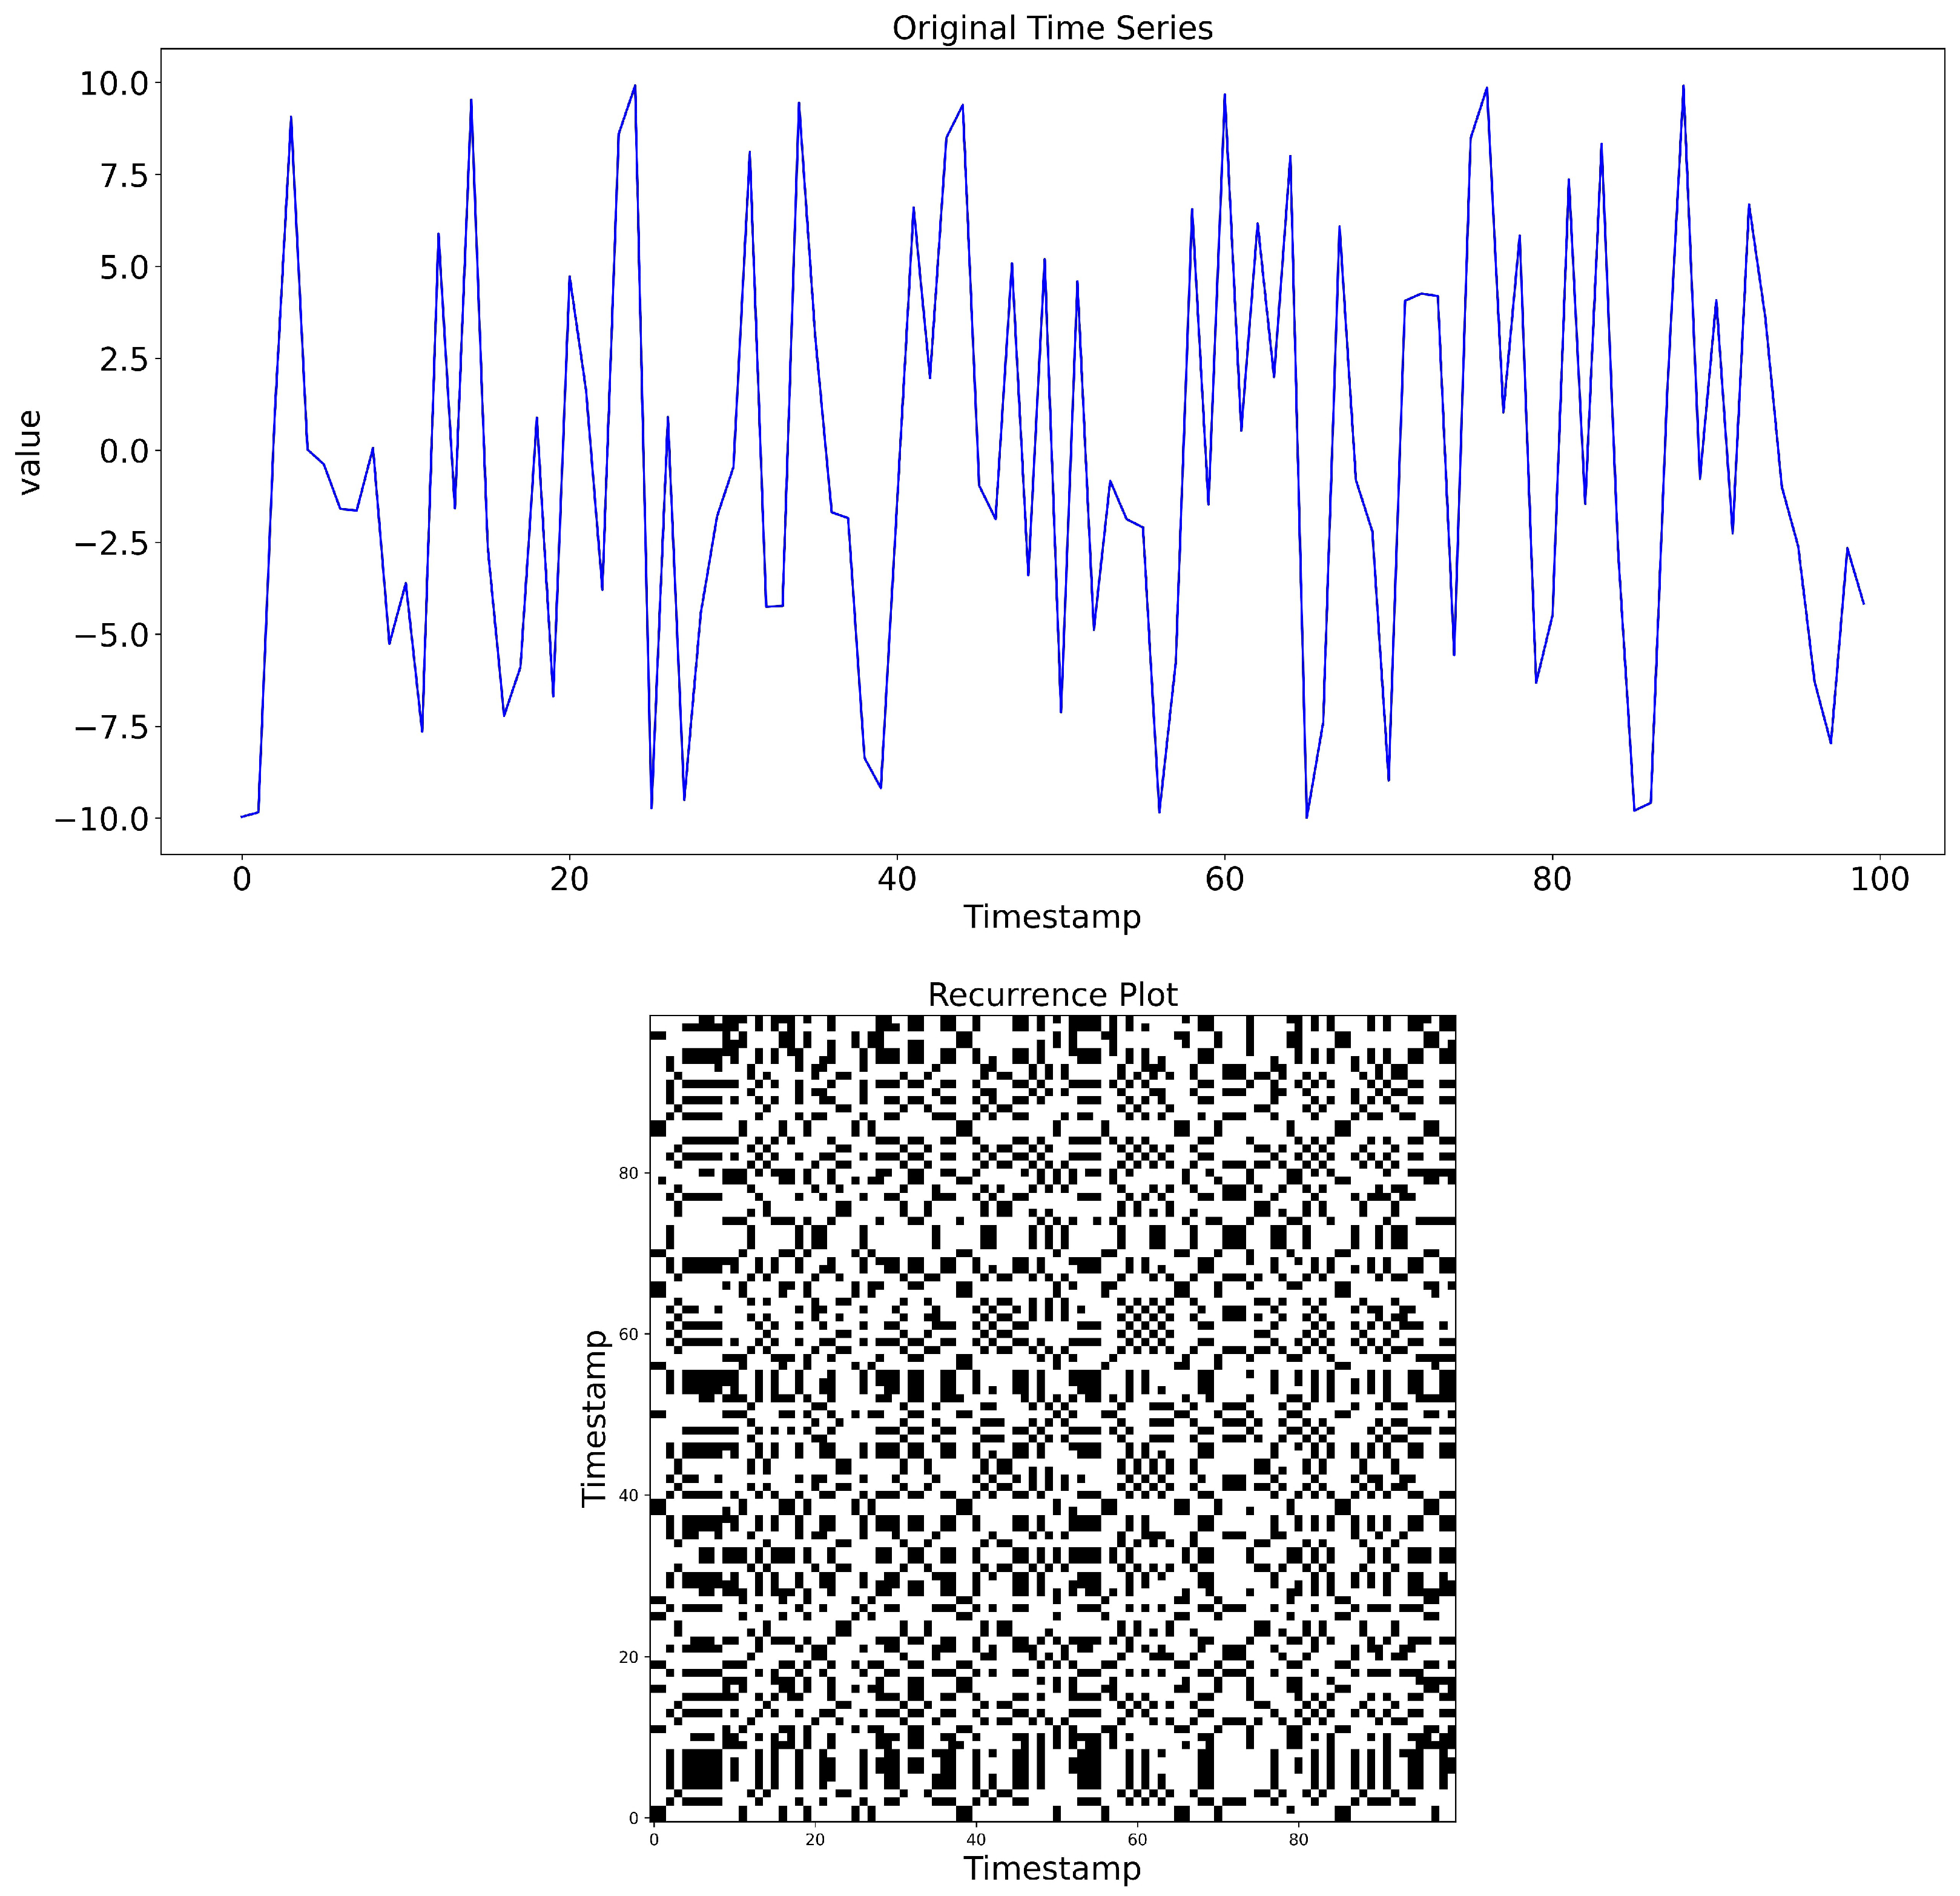
Figure 4.
Example 2 of RP of time series.
2.2.2. Gramian Angular Field (GAF)
The GAF represents the temporal correlation between each pair of time series values to produce a meaningful image. The core of the GAF is a Gramian matrix, denoted by G, which is a useful tool in linear algebra and geometry for calculating the linear dependence of a set of vectors. The Gramian matrix of a vector set is defined by the dot product, also known as the inner product, of each pair of vectors to measure the degree of similarity between them. The dot/inner product between two vectors u and v is defined as
If the u and v vectors are unit vectors, whose norm is 1, then the related inner product is characterized exclusively by the angle () (expressed in radians) between two vectors as follows. The Gramian matrix of (n) unit vectors is defined as
When the () angle between the two considered vectors is closer to
- , the two vectors are similar;
- , the two vectors are orthogonal;
- , the two vectors are opposite.
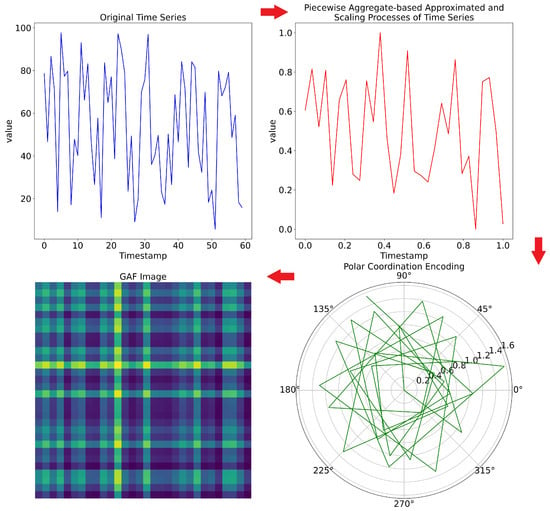
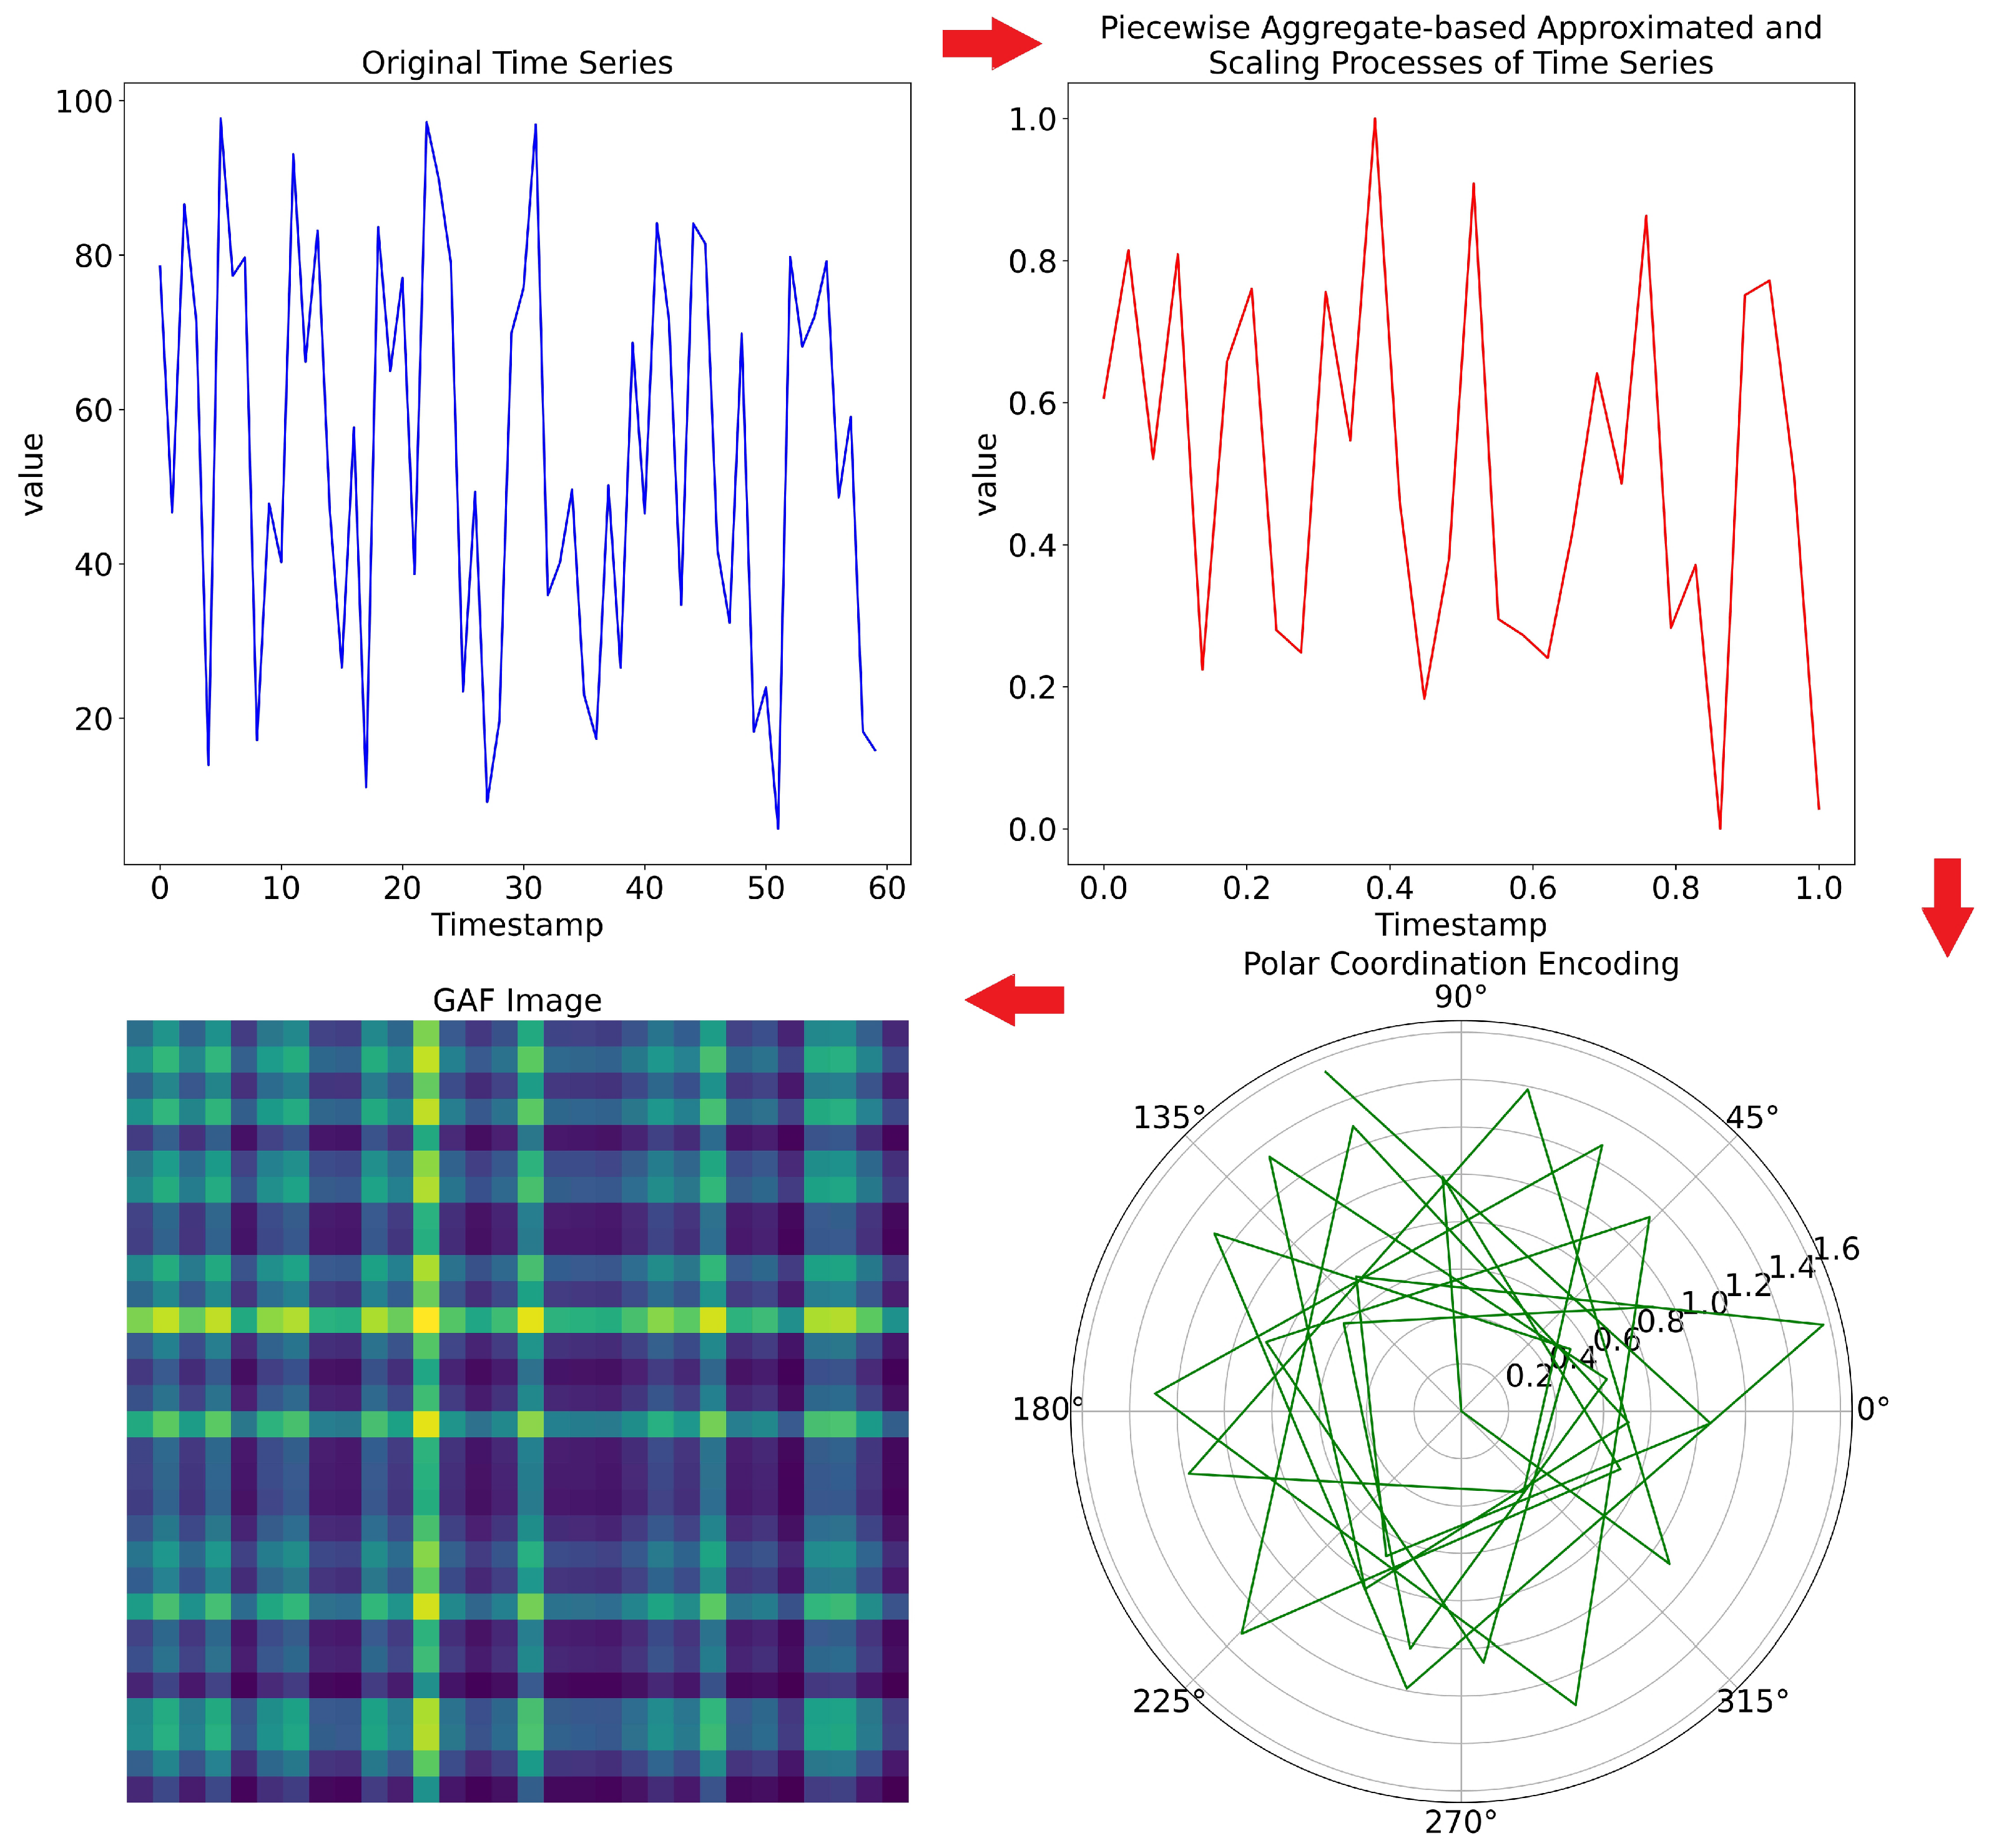
The GAF technique for the time series, which consists of l samples, involves the following steps, as shown in Figure 5 [18]:
Figure 5.
Workflow for encoding raw time series data as images using GAF technique.
- A Min-Max Scaling process is applied to transfer the time series onto the range.
- A Polar Encoding of each sample () within the scaled time series is calculated as follows:where is the time stamp.
- The Gramian matrix can be defined by two types of fields that encode the time series signals into images:
- Gramian angular summation field (GASF) matrix:
- Gramian angular difference field (GADF) matrix:
- Generation of related GAF image.
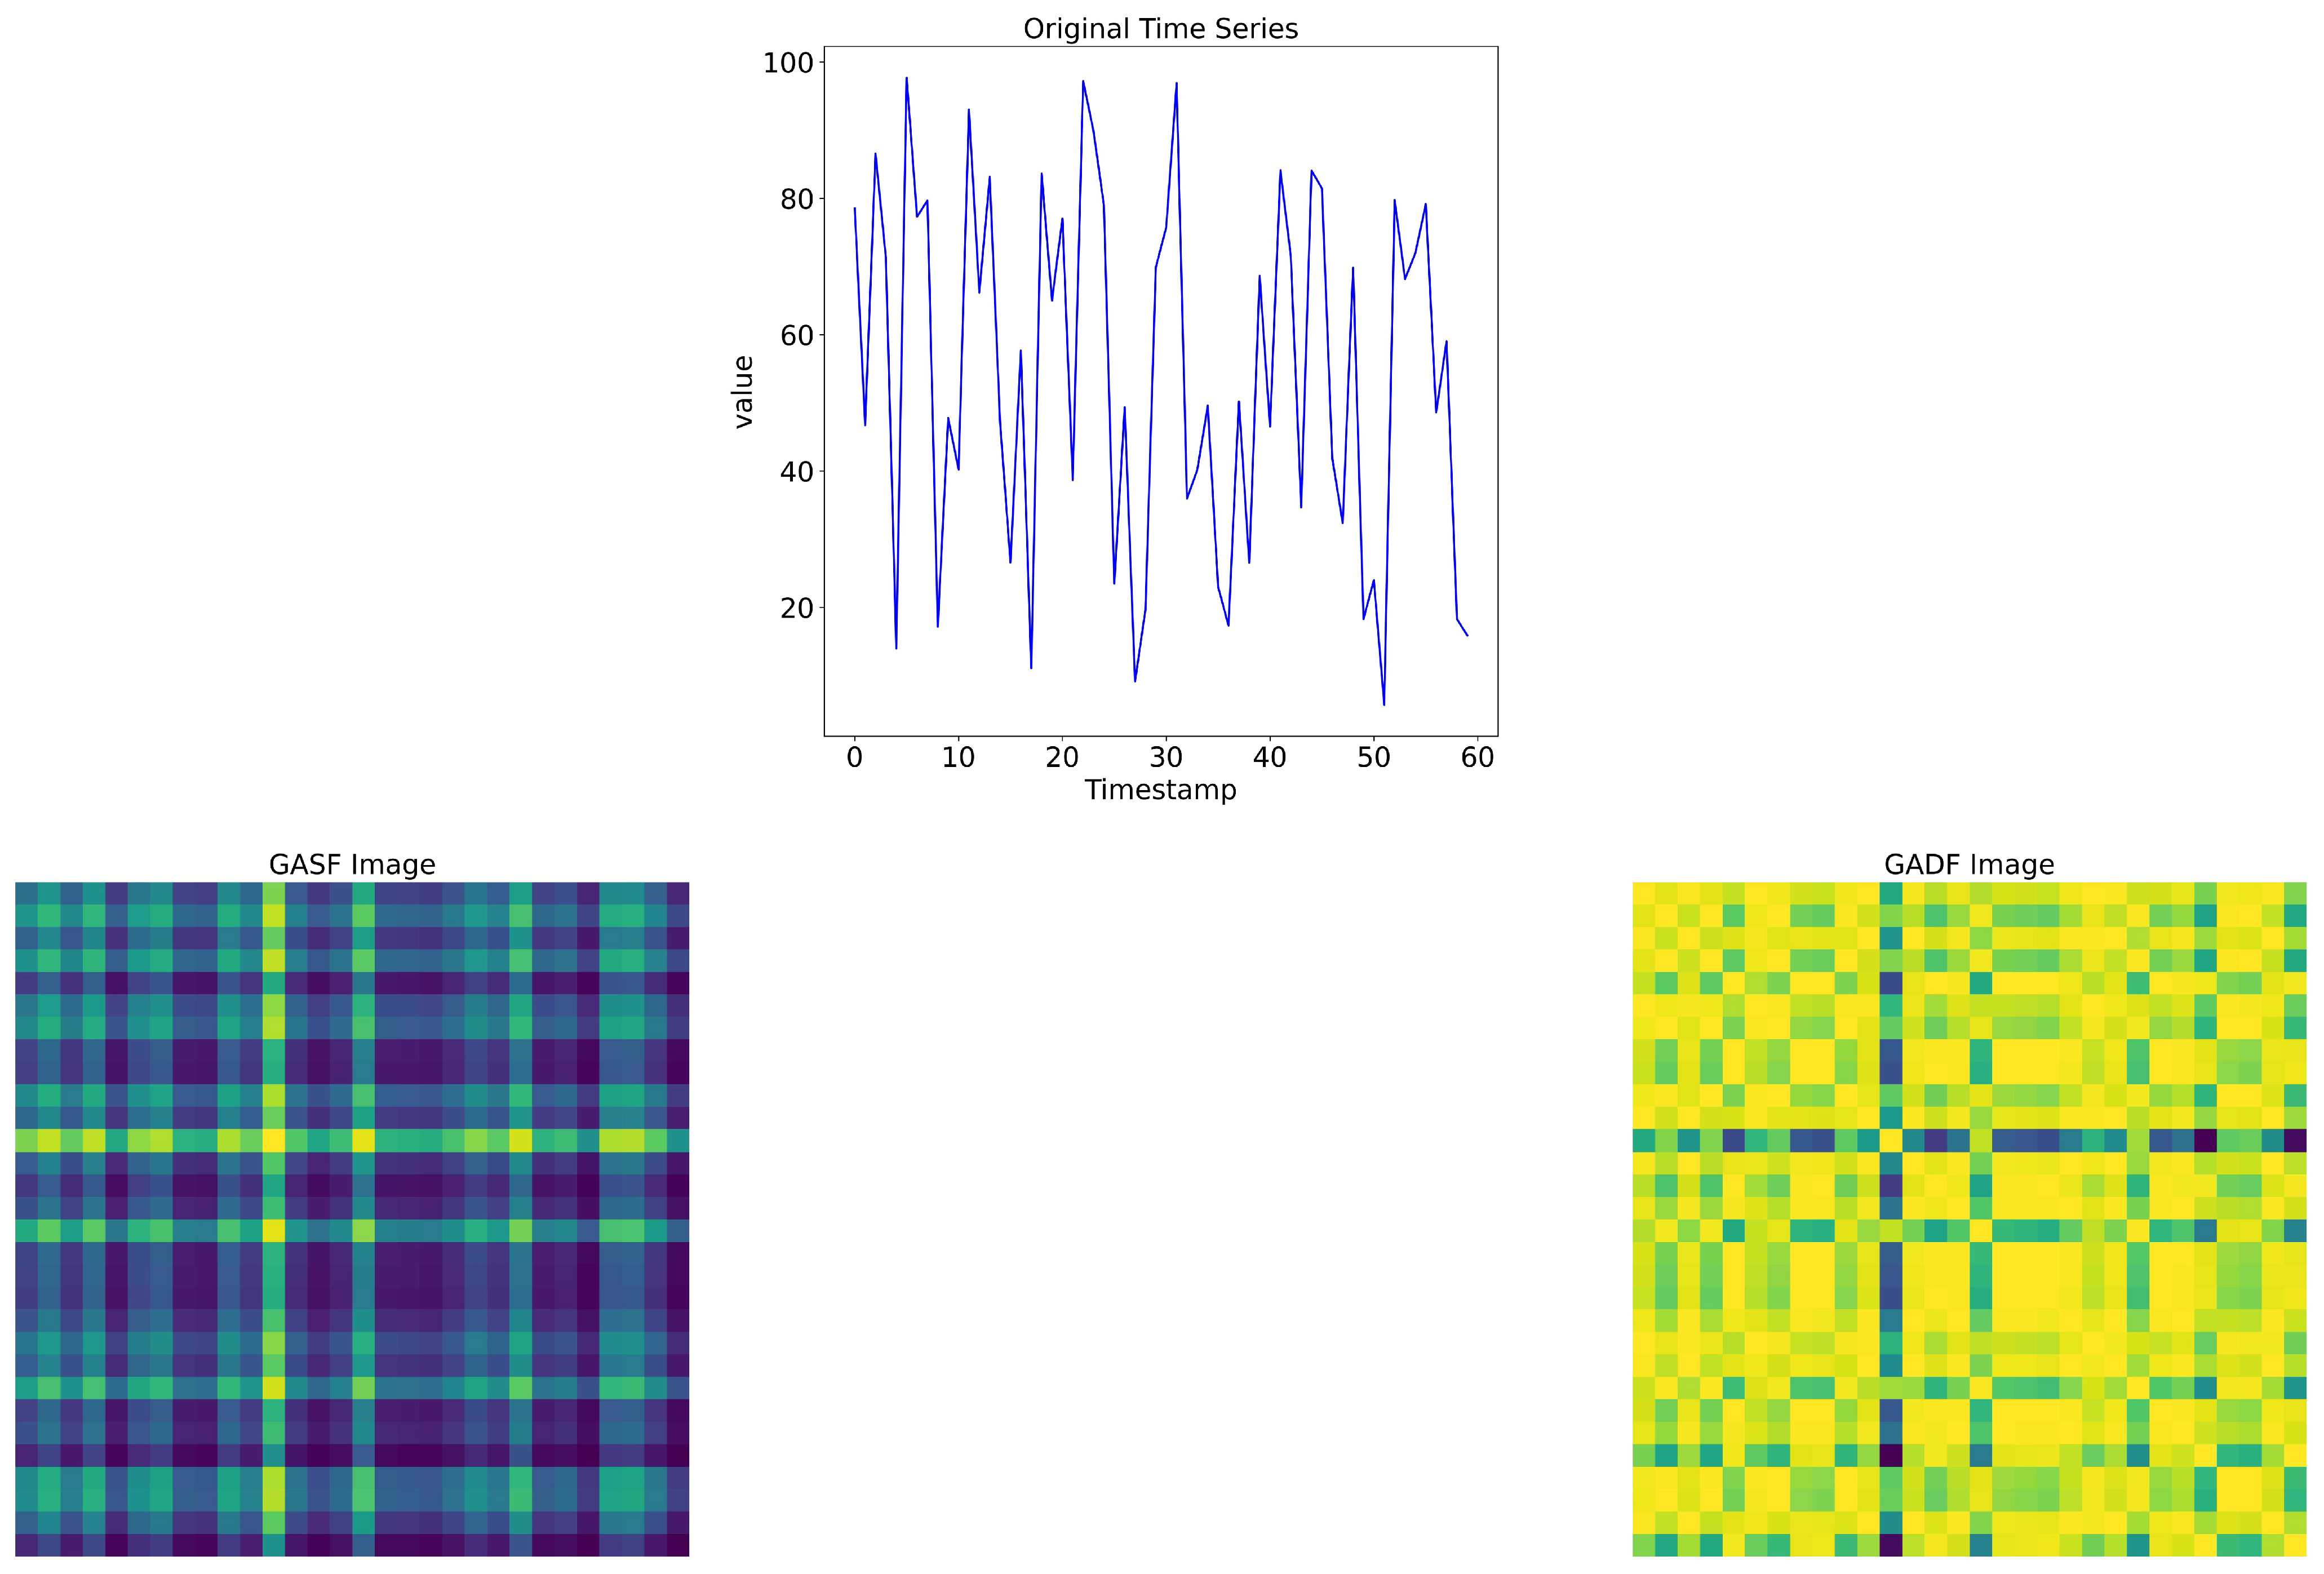
Figure 6 shows an example of the GASF and GADF images of the time series.
Figure 6.
Example time series signal (top); images of GASF and GADF matrix transformation (bottom).
2.2.3. Markov Transition Field (MTF)
The MTF represents the transition probabilities between each pair of values in the discretized time series, used to obtain a relevant image. The Markov transition matrix, a known stochastic or probability matrix denoted by P, is the core of the MTF. This matrix is a square matrix representing the transition probabilities of the state to another during one time step/unit of motion in the phase/state space of the dynamical system [29]:
where
- is the probability of the transition of the () form (i) state to the (j) state during one time step/unit of motion in the state space.
- Q is the number of states/size of the state space of the considered dynamical system.
The Q parameter indicates the number of discretized areas, or quantile bins, within the value range of the time series of the variable. Identifying the Q parameter defines the dimensions of the Markov transition matrix that represents the state space of the system under consideration. The values in the matrix cells represent the probability of transitioning between two states during motion in the state space, as described in Formula (8). Therefore, the Q parameter must be identified carefully to accurately describe the system’s dynamics. Identifying the Q parameter requires analyzing the temporal and periodic features of the original time series. The higher the Q parameter value, the higher the MTF image resolution. This provides more information about the probability of transitioning between any two states during timely motion in the state space. Thus, it is assumed that this will positively affect the performance of the CNN classifier, taking its structure into account, of course.
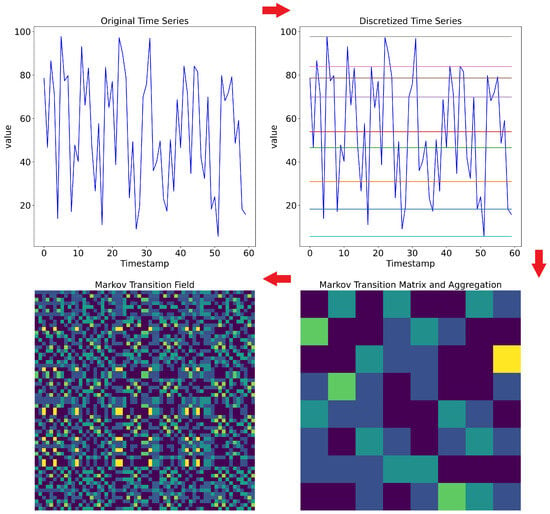
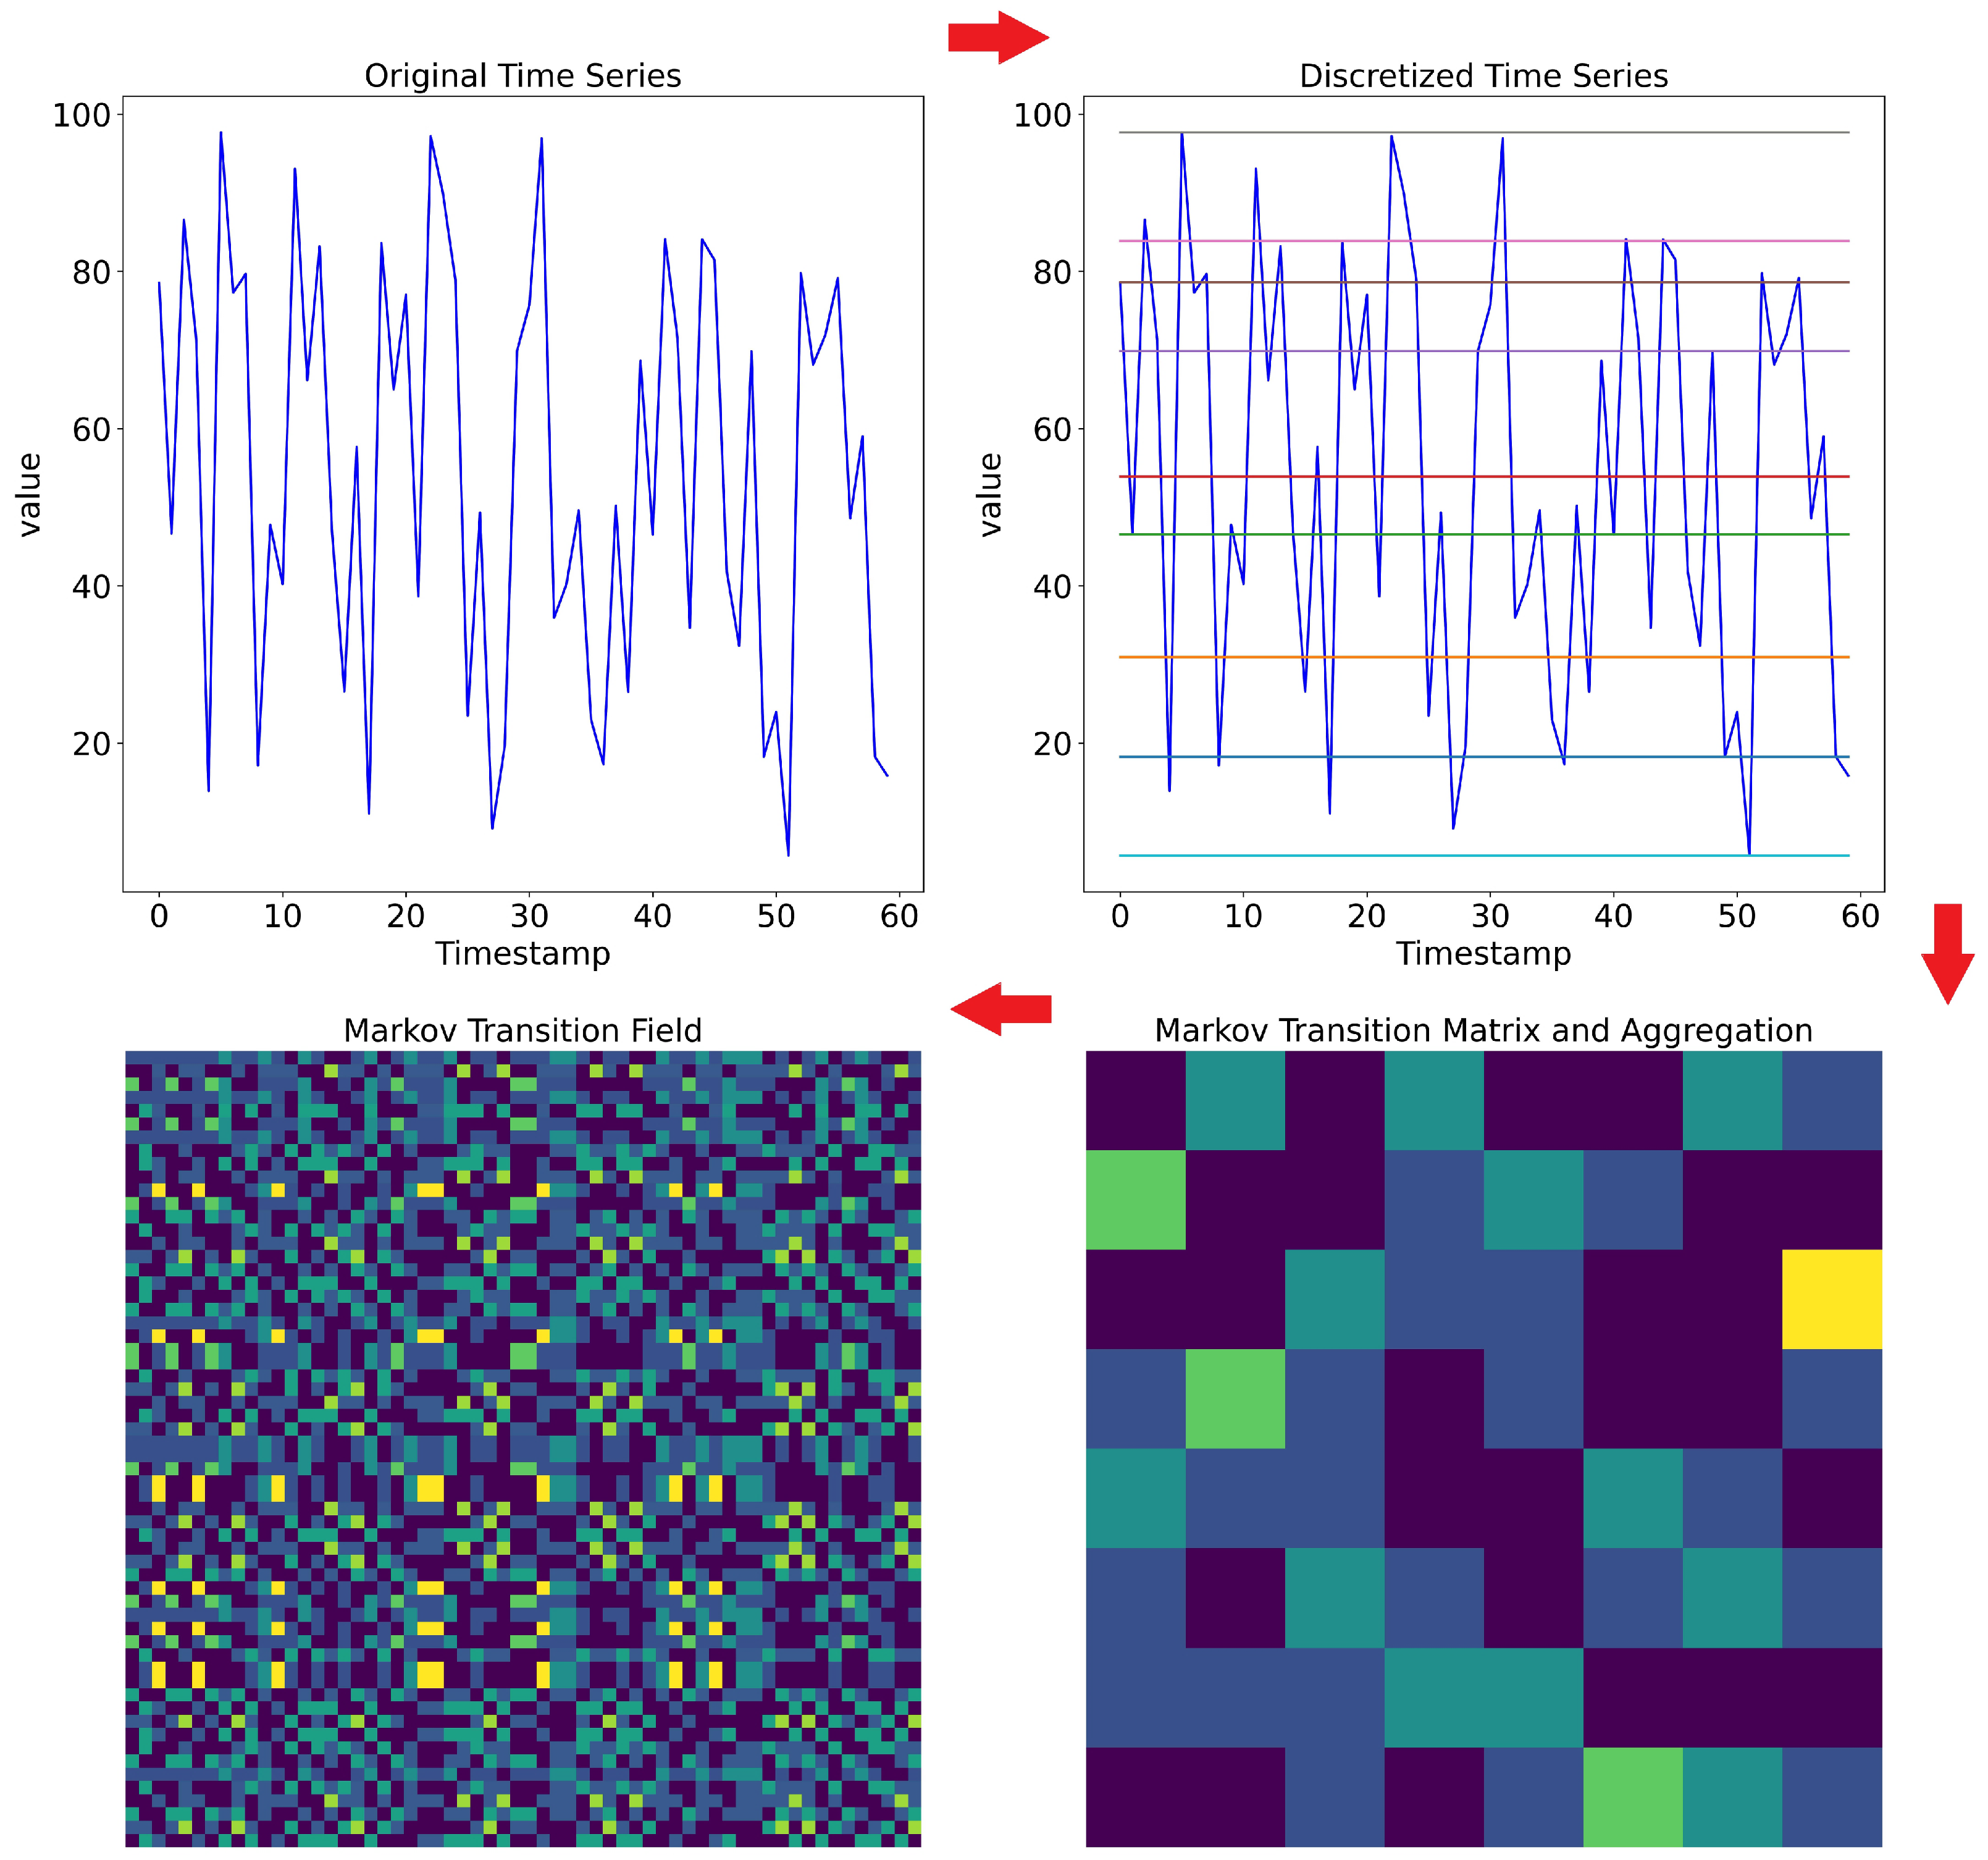
The MTF method as the imaging time series technique consists of the following steps, as shown in Figure 7 [18,29]:
Figure 7.
Workflow for encoding raw time series data as images using the MTF technique.
- Discretize the time series to quantile bins.
- Build the Markov transition matrix.
- Compute transition probabilities.
- Compute the Markov transition field.
- Compute an aggregated MTF.
2.3. Convolutional Neural Networks as Deep Learning Systems Applied to Imaging Time Series Datasets
2.3.1. Convolutional Neural Networks (CNNs)
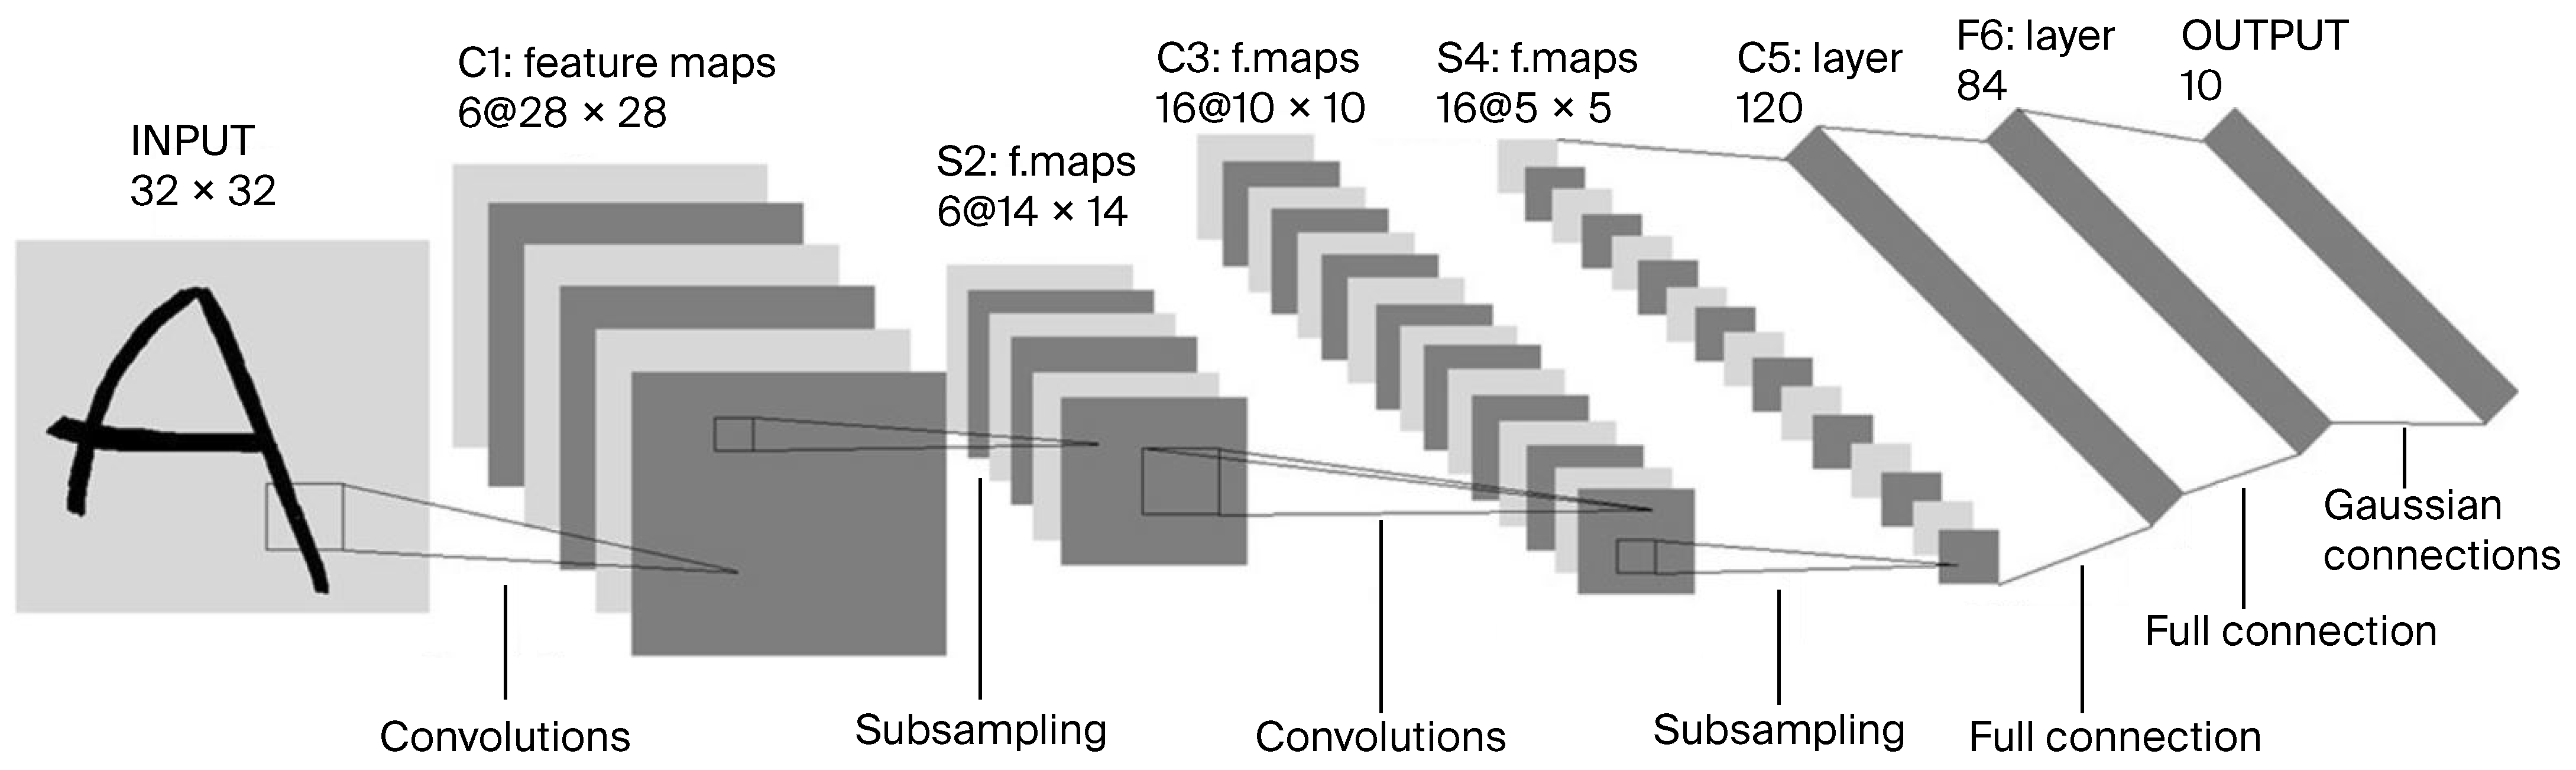
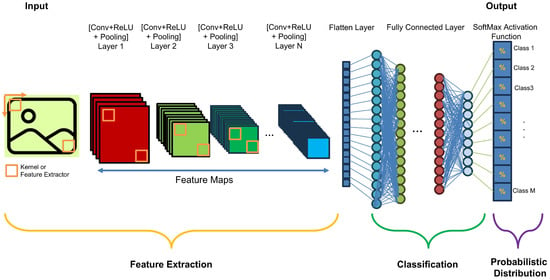
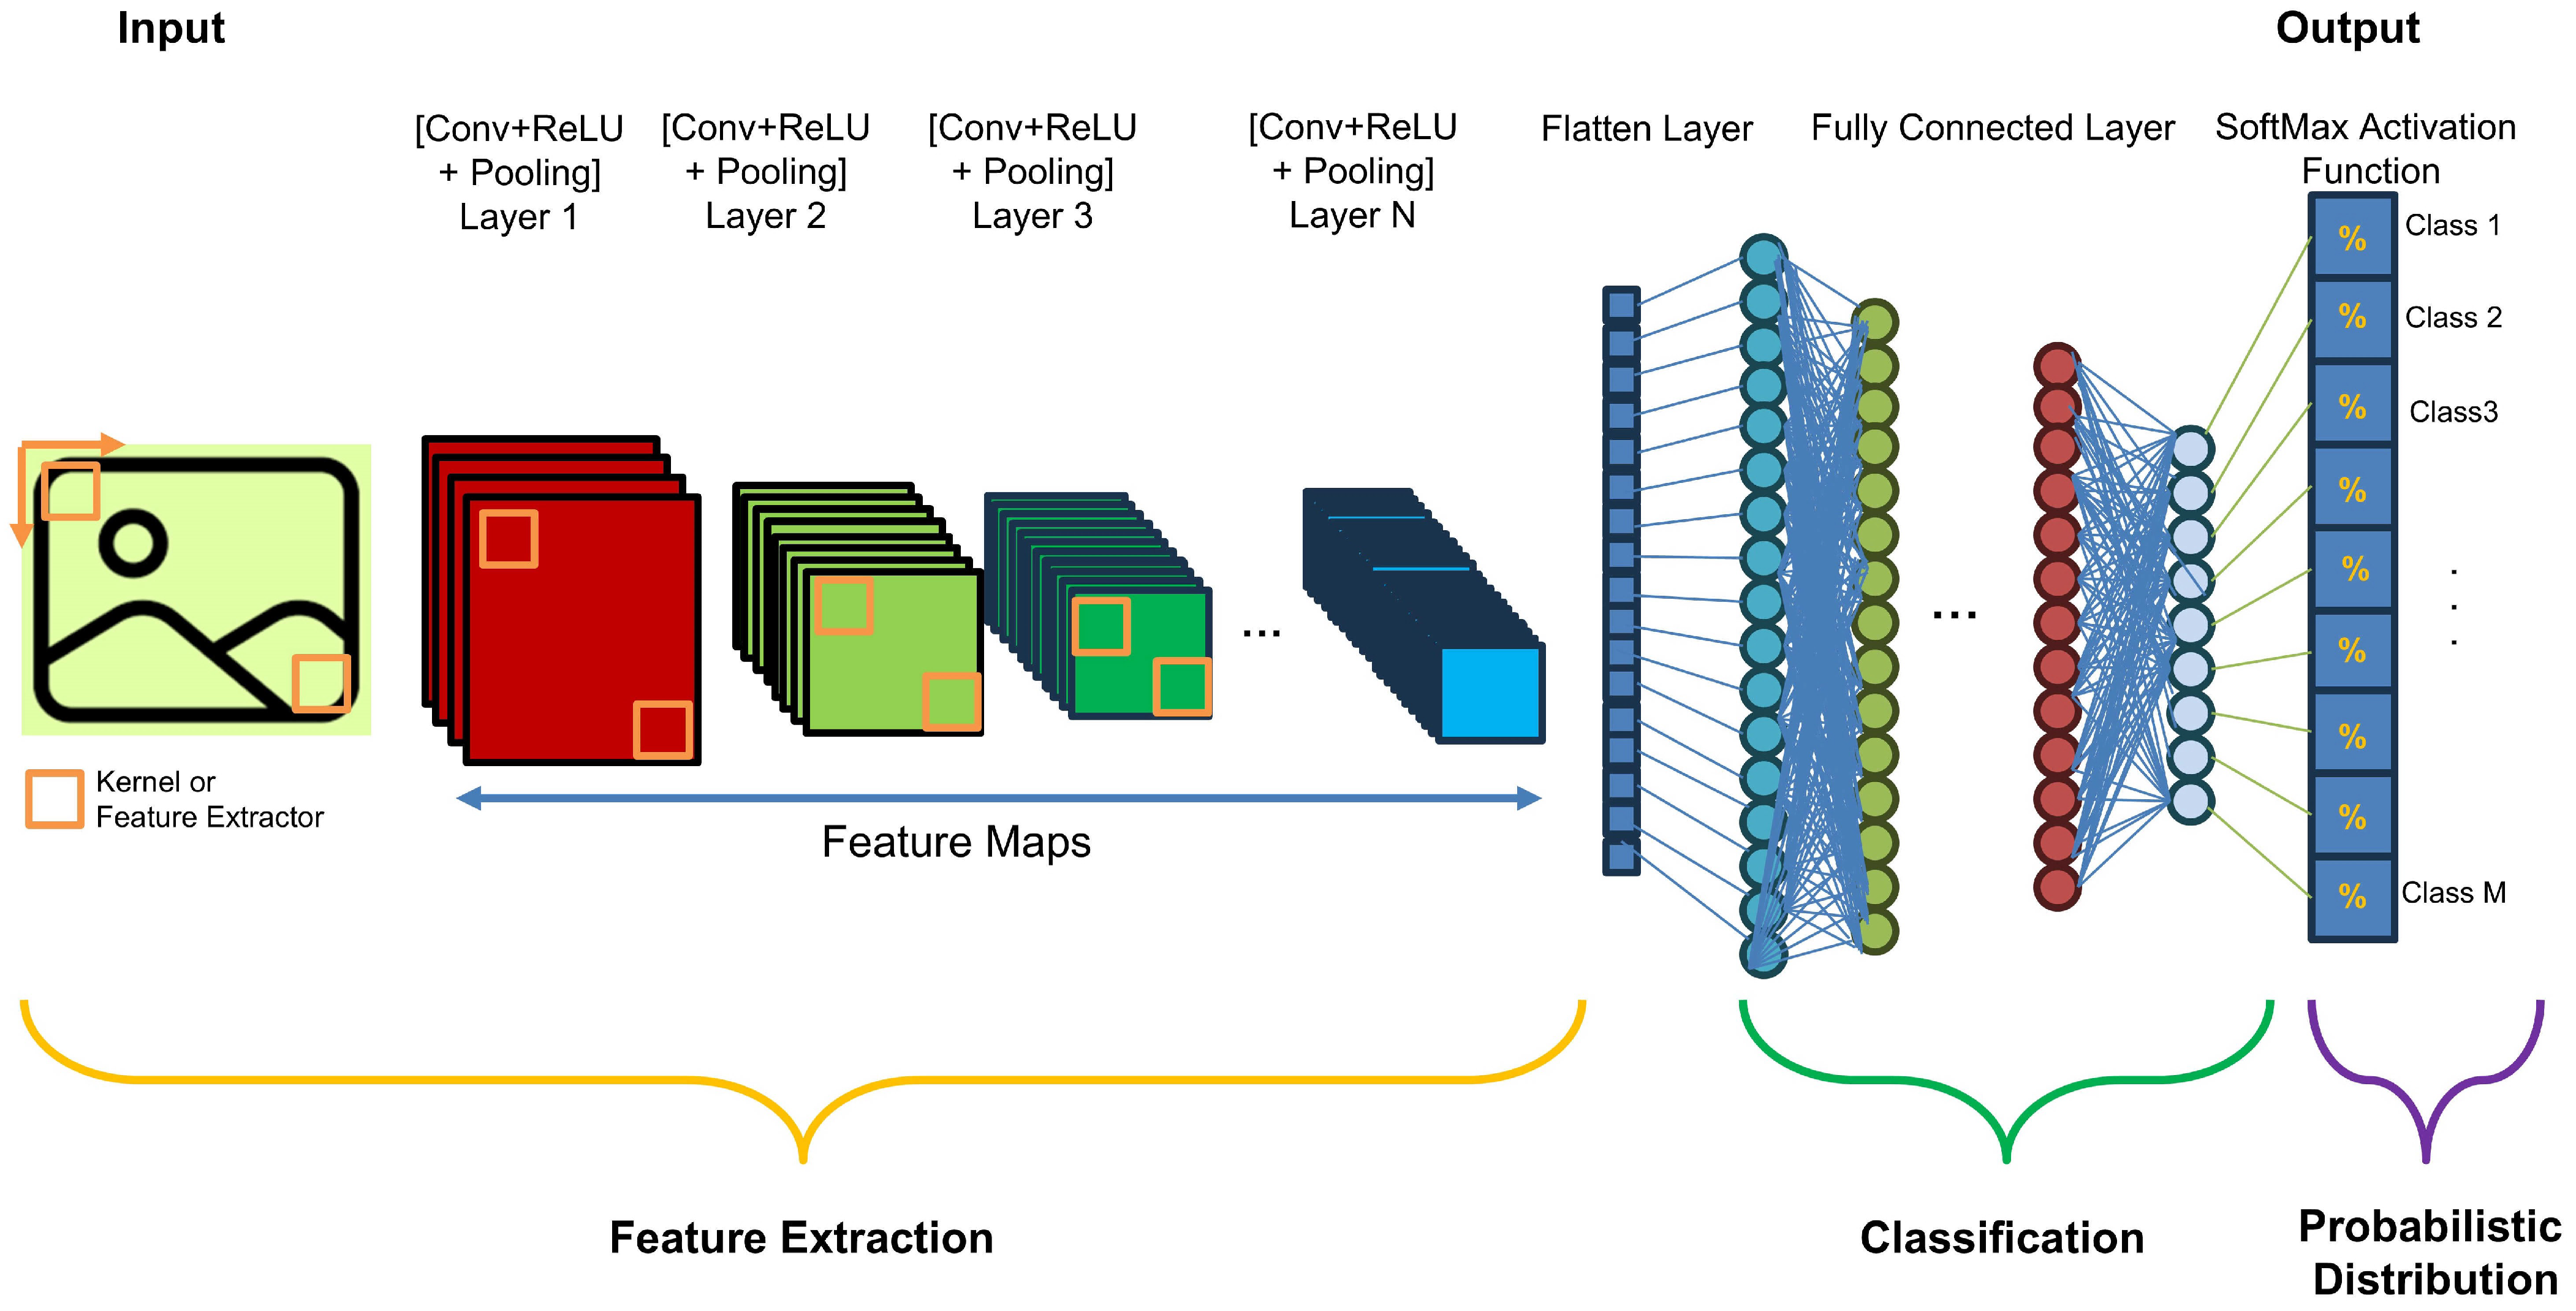
The visual cortex-based neocognitron network, proposed by Fukushima in 1980 [30], was further developed into a CNN by LeCun et al. [31] with the famous LeNet-5 architecture to recognize handwritten digits, as illustrated in Figure 8. The general structure of a CNN consists of the following blocks, illustrated in Figure 9 [32,33]:
Figure 8.
LeNet-5 architecture [31].
Figure 9.
General CNN structure.
- Feature Extraction:
- Convolutional Layer: Basically, a convolution is defined as a mathematical operation in which two sets of information are merged to create a new set that contains more informative information about the task at hand. In this sense, the first information set is considered an image represented as a 2D matrix with one or three channels. The second information set is a convolution filter, usually a square matrix with dimensions of 2, 3, etc., that extracts specific features. These features can be low-level (such as contours, edges, angles, and colors) or high-level (such as shapes and objects). The extracted features are collected together to create a 2D “feature map.” The convolution process can also be applied to the feature map generated from the previous layer to create a new feature map with more complex and intricate features than the original.
- Nonlinear Activation Layer: It consists of nonlinear functions, such as the rectified linear unit (ReLU) and sigmoid functions. The correlation between the convolution process and the nonlinearity process (1) enables the network/model to learn/build complex representations and relationships with a “nonlinearity property” of the input/output data/information and (2) prevents the exponential growth of the computation required to run the neural network.
- Pooling Layer: In this step, the size of the feature map generated by the (Convolution + ReLU) layer is subsampled through the aggregation of features from local regions to learn invariant features and reduce computational complexity. In this process, the m-square matrix (usually or ) is shifted over the processed feature map using a predefined step called the stride. For each shift, a value (e.g., the average, maximum, or minimum) is computed and substituted in place of the originally processed values in the new feature map.
Sequences of these layers (convolutional layer, nonlinear activation function, and pooling), called hidden layers, can be stacked several times, and their final output yields the feature map. The deeper the feature extraction block of the CNN, the more complex the feature map, i.e., the feature map starts with low-level features and then becomes more complex as it passes through each hidden layer until it reaches high-level features at the end of the feature extraction block. - Flattening Layer: The final output of the last (Convolution + ReLU + Pooling) sequence is the last layer in the feature extraction stage and is formatted as a 2D matrix. However, the classification stage in the CNN model requires input to be formatted as a 1D matrix; thus, the “Flatten” process should be applied.
- Classification: The extracted and flattened features maps of the considered states will be processed by a Fully Connected (FC) network that consists of several feedforward layers.
- Probabilistic Distribution: To ensure that the considered classes follow a probabilistic distribution, a SoftMax Activation function is usually applied.
The CNN structure can also include other types of layers, such as dropout and/or batch normalization, to solve, for example, overfitting problems. The popular state-of-the-art CNN architectures are (1) LeNet-5 (1998), (2) AlexNet (2012), (3) ZFNet (2013), (4) GoogLeNet/Inception (2014), (5) VGGNet (2014), and (6) ResNet (2015) [33].
2.3.2. CNN Classification Systems Based on Time Series-to-Image Encoding
A brief review of some CNN classification systems based on time series-to-image encoding, as proposed in [1,20], is provided below:
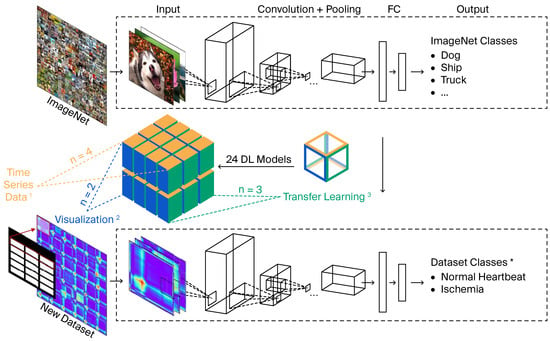
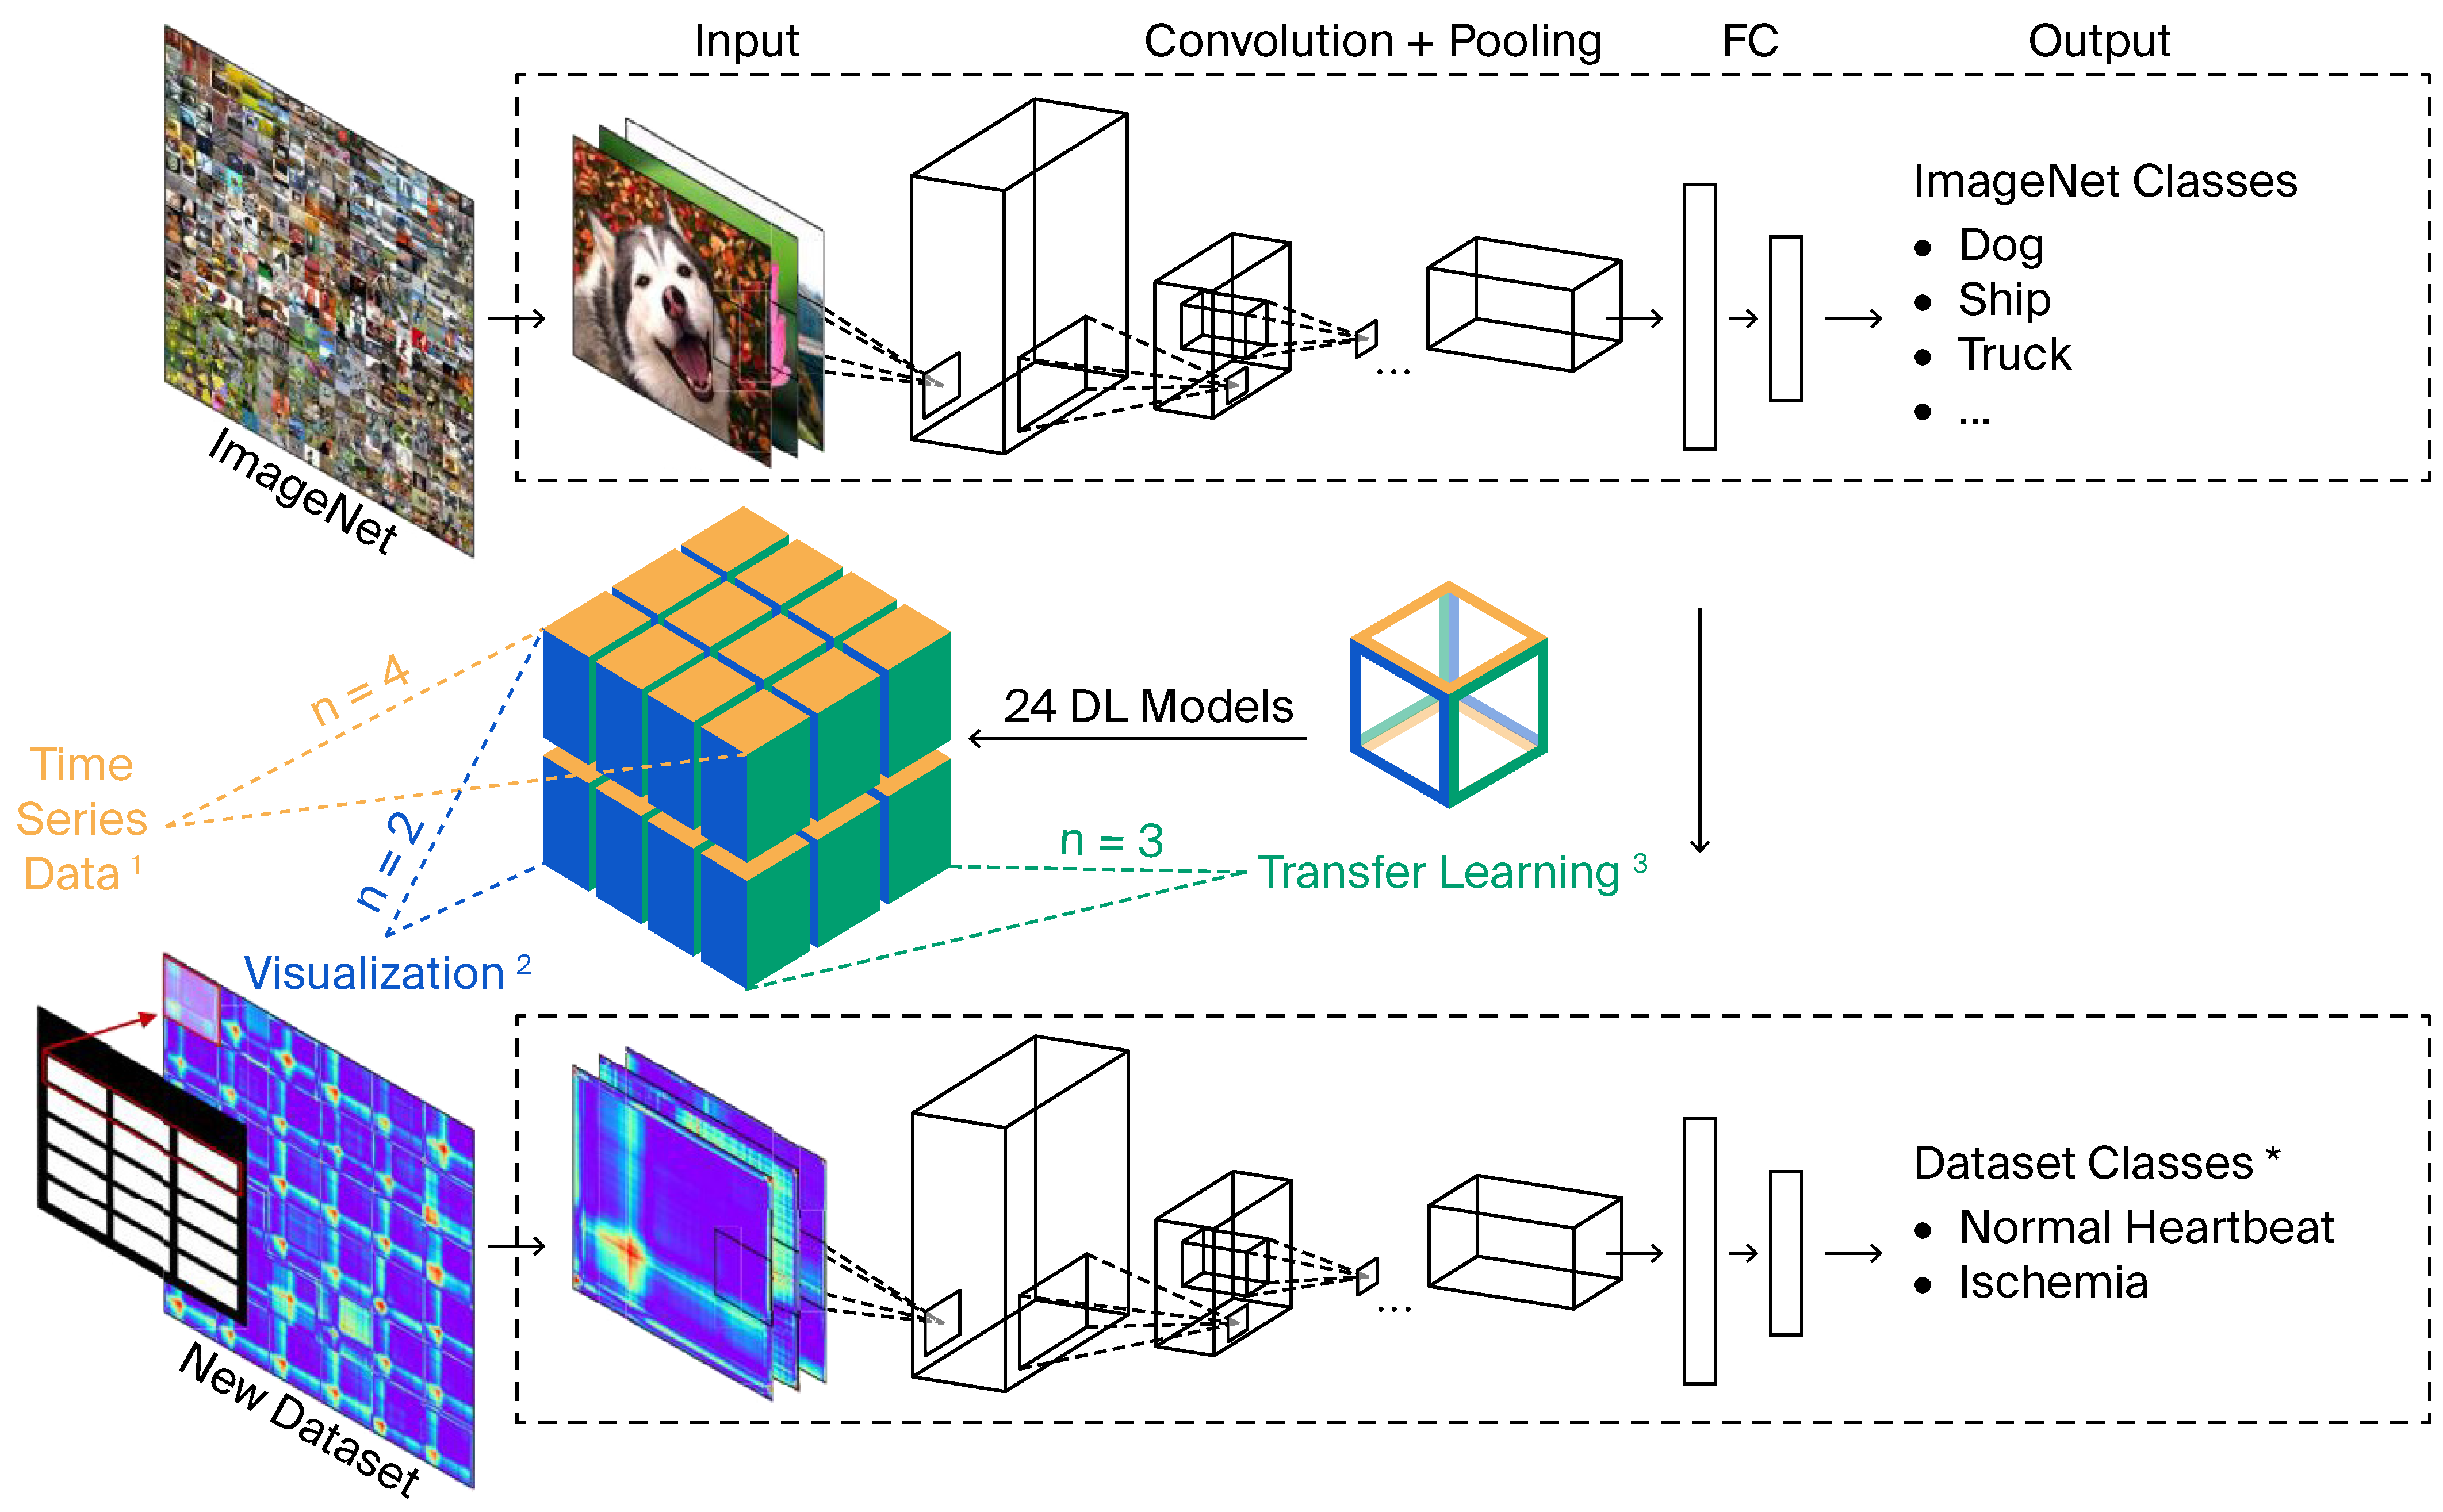
- Gross et al. [1] suggested the following concepts for building the classification system of a time series, as illustrated in Figure 10 [1]:Figure 10. Workflow of the benchmarking transfer learning strategy for time series imaging, proposed in [1].
- Use the GAF, GASF, and GADF as time series imaging techniques to image the considered time series dataset;
- Employ benchmarking transfer learning strategies to improve the learning of new tasks through knowledge transfer from a related task that has already been learned (such as VGG16, VGG19, ResNet50V2, and Xception).
To evaluate the transfer learning strategies for benchmarking time series imaging, the following datasets were used, whose numerical specifications are listed in Table 1 [34]:Table 1. Overview of datasets used in [1].- (a)
- Computers: These problems were taken from data recorded as part of a government-sponsored study called Powering the Nation. It aimed to collect behavioral data about how consumers use electricity within the home to help reduce the UK’s carbon footprint. The data contain readings from 251 households, sampled in two-minute intervals over a month. Each series is 720 data points long (24 h of readings taken every 2 min). Its classes are Desktop and Laptop.
- (b)
- DodgerLoopGame: Traffic data were collected with a loop sensor installed on a ramp for the 101 North freeways in Los Angeles. This location is close to the Dodgers Stadium; therefore, traffic is affected by the volume of stadium visitors. Class 1: Normal Day; Class 2: Game Day.
- (c)
- ECG200: Each series traces the electrical activity recorded during one heartbeat. The two classes are normal heartbeat and Myocardial Infarction.
- (d)
- AbnormalHeartbeat: Heartbeat recordings were gathered from both the iStethoscope Pro iPhone app and from clinical trials using the digital stethoscope DigiScope. The time series represent the change in amplitude over time during an examination of patients suffering from any four common arrhythmias.
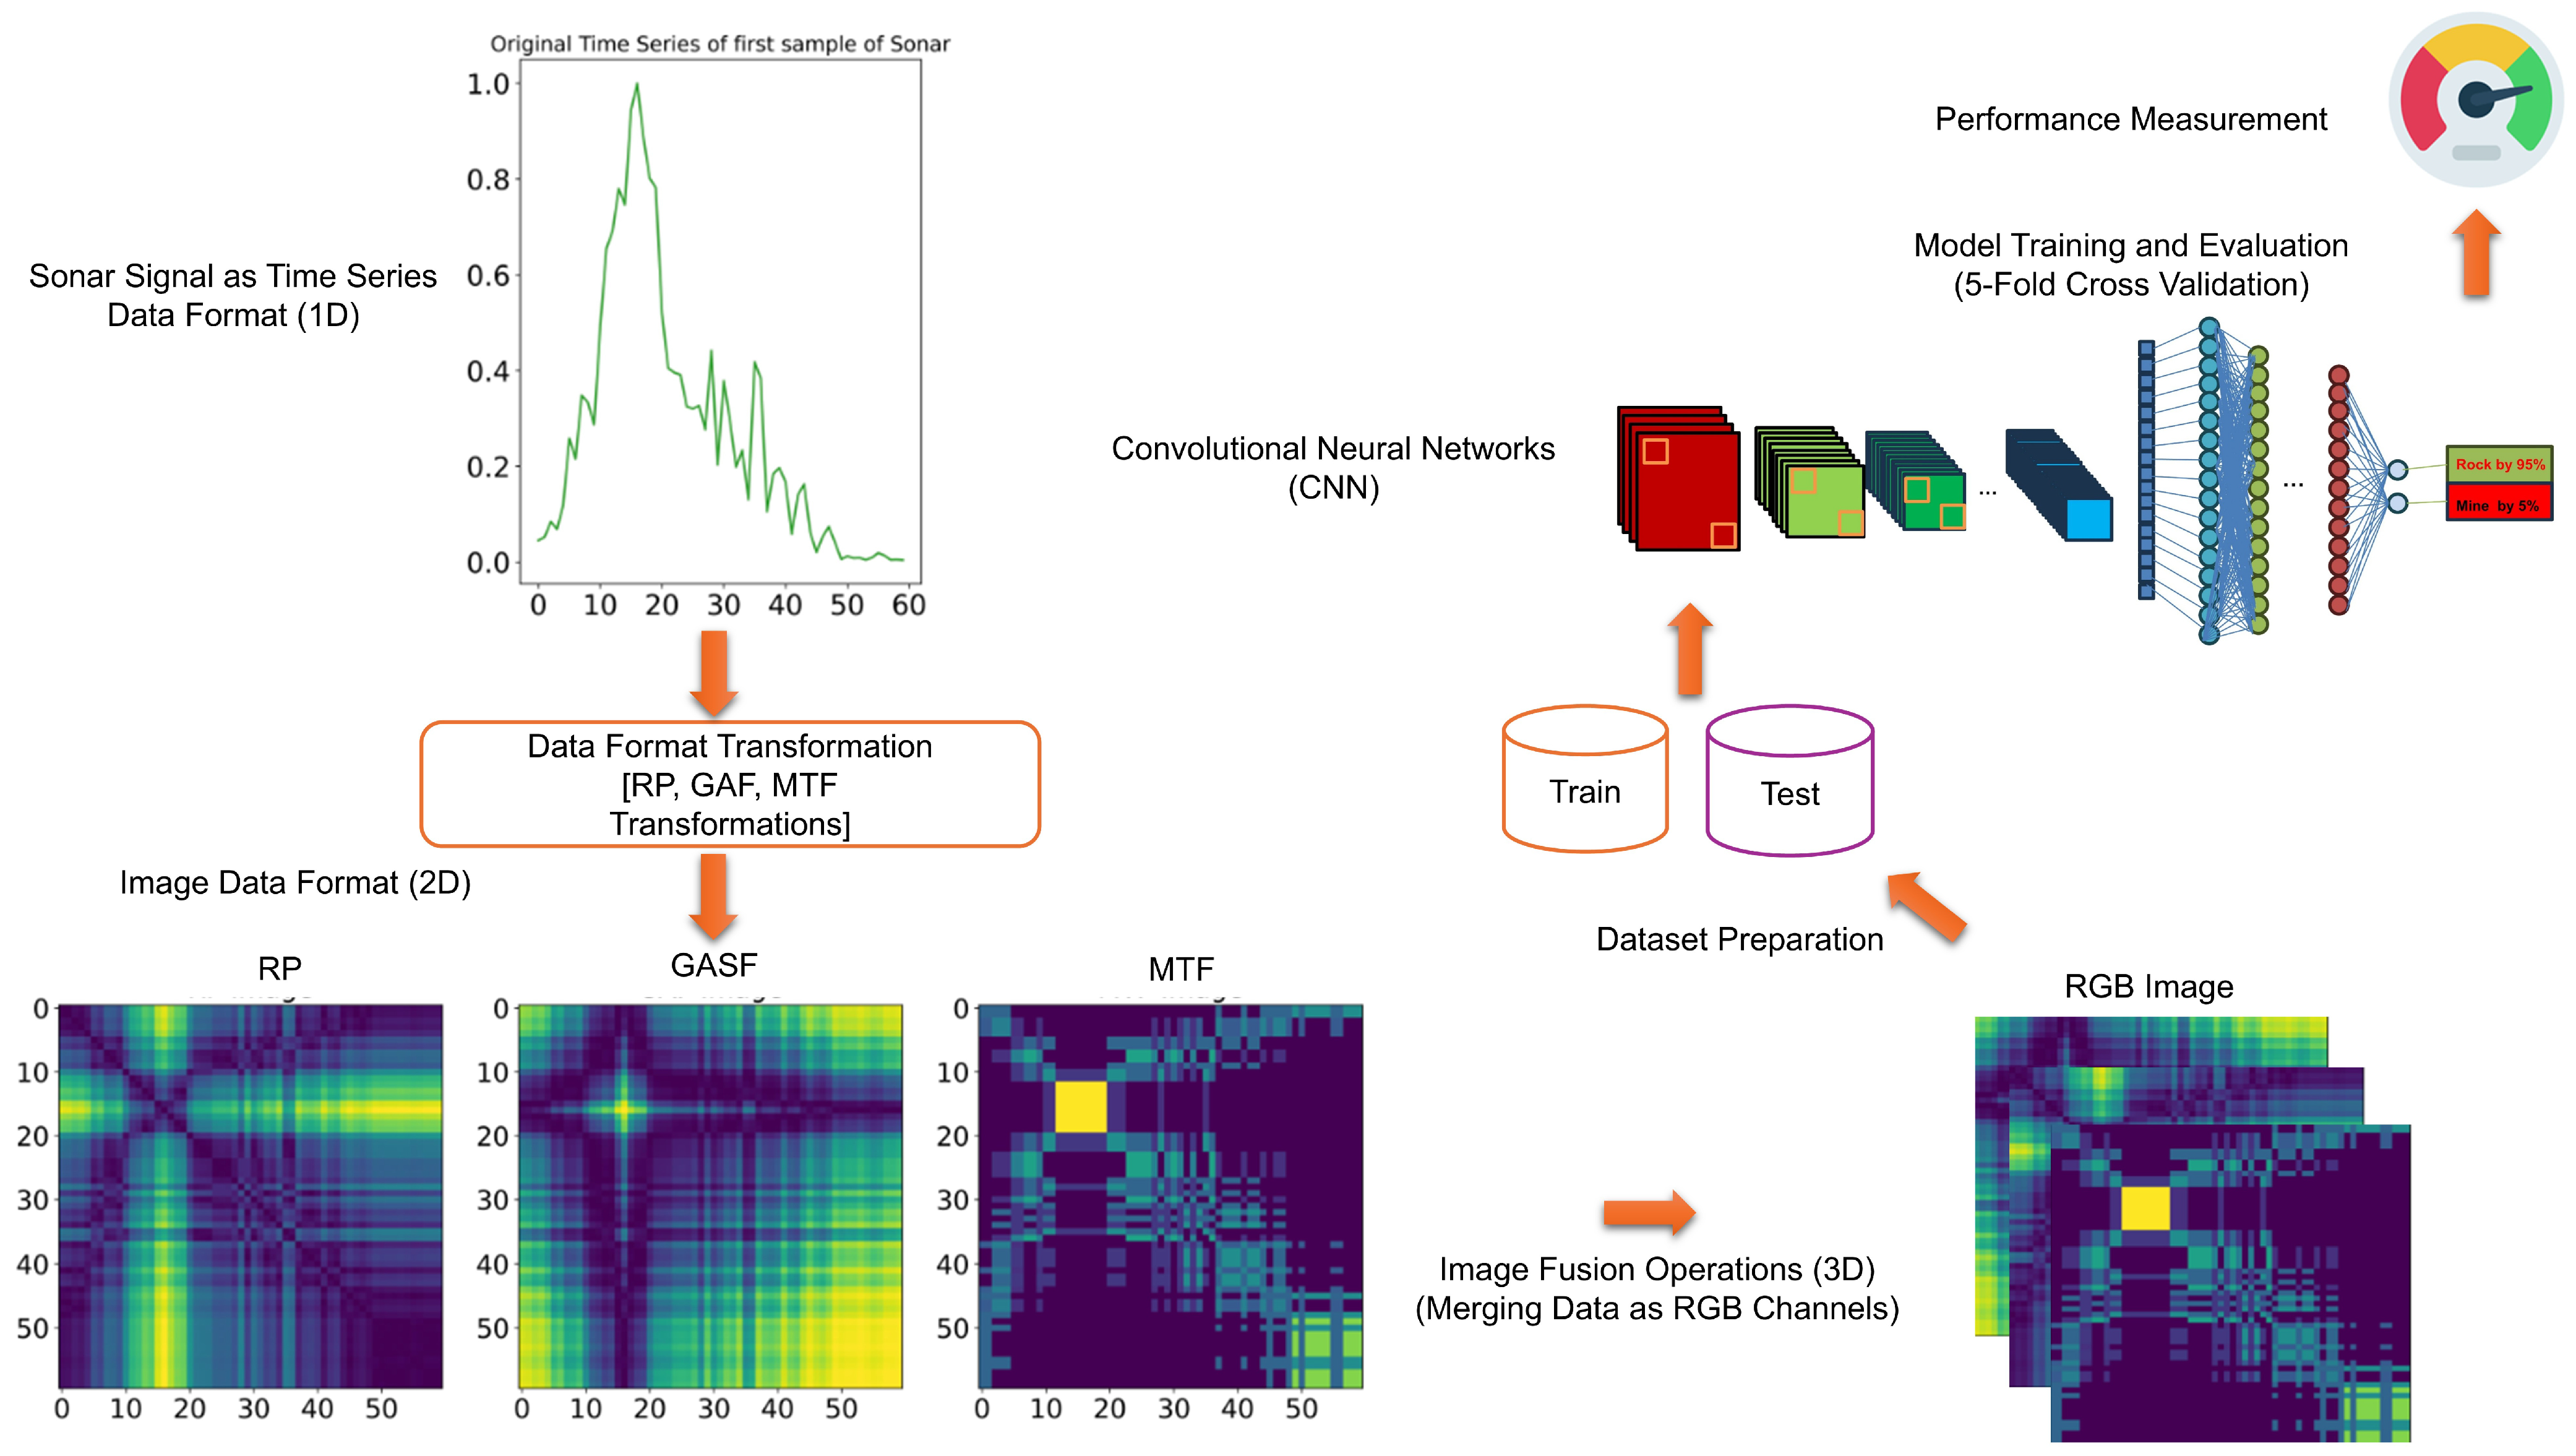
- Buz et al. [20] developed another approach and application of time series-to-image transformation methods for classifying underwater objects (sonar signals), as shown in Figure 11. The sonar dataset developed by Gorman et al. [35] was used to evaluate Buz et al.’s method. This dataset contains the signals reflected from cylindrical mines and cylindrical rocks resembling these mines from different angles. The dataset contains 208 samples in time series format, where 111 samples belong to cylindrical mines and 97 samples to cylindrical rocks. The length of each time series is 60 numbers, ranging from 0.0 to 1.0. Each number represents the energy collected over a fixed period in a given frequency band [35].Figure 11. CNN architecture of proposed classification system for time series proposed in [20].The core of the comparative analysis is the conversion of the sonar time series dataset into the related and individual 2D image dataset through the separate application of the GASF, MTF, and RP techniques. Then, the three related 2D image datasets are merged to generate a 3D image for each sample in the sonar dataset, as shown in Figure 12. The resulting 3D image dataset is used to train and evaluate the CNN architecture shown in Figure 11.Figure 12. Classification system of time series proposed in [20].
3. Novel Approach for Time Series-to-Image Encoding for Convolutional Neural Network-Based Classification
3.1. Grayscale Fingerprint Features Field Imaging Techniques
3.1.1. Motivation
Based on the mathematical background and the transformation processes used in state-of-the-art imaging time series techniques, we found that
- The transformation processes are characterized by a high degree of complexity.
- The resulting image structure exhibits diagonal symmetry, resulting in the presence of redundant and duplicated information.
- The resolution of an image is directly proportional to the square of the number of descriptive features of the time series data under consideration. Consequently, as the number of features increases, the image resolution improves. However, this enhancement in resolution necessitates a proportional increase in the time required to process the image, thereby achieving the desired objectives, such as classification.
In time series imaging research, the term “robust” means that the resulting image should capture and maintain the temporal features of the time series in question. These features are the main factor in expressing the system or phenomenon under consideration and achieving the robustness and high performance of the deep learning structure used as a classifier.
To avoid the complexity and high computation time associated with the state-of-art techniques of time series imaging, the following solutions are proposed:
- Only a transformation process based on two simple steps is applied to transfer the descriptive features/variables of each sample of the time series into the 2D image.
- The resulting image has a non-symmetric property, and its resolution is equal to the number of descriptive features/variables of the transformed sample.
These solutions can be realized via Grayscale Fingerprint Features Field Imaging(G3FI), a novel imaging time series technique.
3.1.2. Methodology
Any time series imaging technique should capture the states and observed values of the system or phenomenon being studied, as well as the correlations between them. Additionally, the space should encompass all variables representing each time point throughout the entire observation period. This can be achieved using a sample-specific or local representation of the system or phenomenon. A representation is a row in the dataset containing measurements and a collection of all related variables and their values at a specific time point. Conversely, a dataset-wide or global representation, which is a column in the dataset, shows the state space of one variable throughout the entire observation period. However, this representation only considers the correlation statuses of one variable, ignoring other variables representing the same phenomenon or system. Consequently, it will not accurately depict the phenomenon or system, resulting in poor performance when using any imaging time series technique for deep learning, particularly with a CNN model. Furthermore, to develop a CNN model for classification, the standard structure of the image dataset should be such that each image has a distinct class or label. In the context of imaging time series technology, sample-specific representation fulfills this condition because each sample (i.e., row) has a distinct class or label. However, a dataset-wide representation cannot fulfill this condition because it encompasses the entire dataset. Each column will therefore be correlated with more than one class or label.
The vector of the l descriptive features of each considered sample can be defined as
where
- is the ith descriptive feature.
- l is the number of descriptive features used/columns of the multivariate time series dataset.
The proposed generation process corresponding to the grayscale fingerprint is as follows:
- The descriptive features of each sample undergo Grayscale-based normalization, leading to new feature values between zero (black) and 255 (white):where
- is the normalized/scaled vector of the descriptive features of each sample considered.
- is the minimum value of the descriptive features of each sample considered.
- is the maximum value of the descriptive features of each sample considered.
- 255 is the scalar of grayscale processing.
- A G3FI image () is generated by reshaping (Reshape) the grayscale normalized vector of each considered sample into the () matrix as follows:where
- is the reshaping process of the grayscale normalized/scaled vector into the () matrix to generate a G3FI image.
- K is the number of rows in the G3FI image matrix ().
- L is the number of columns in the G3FI image matrix ().
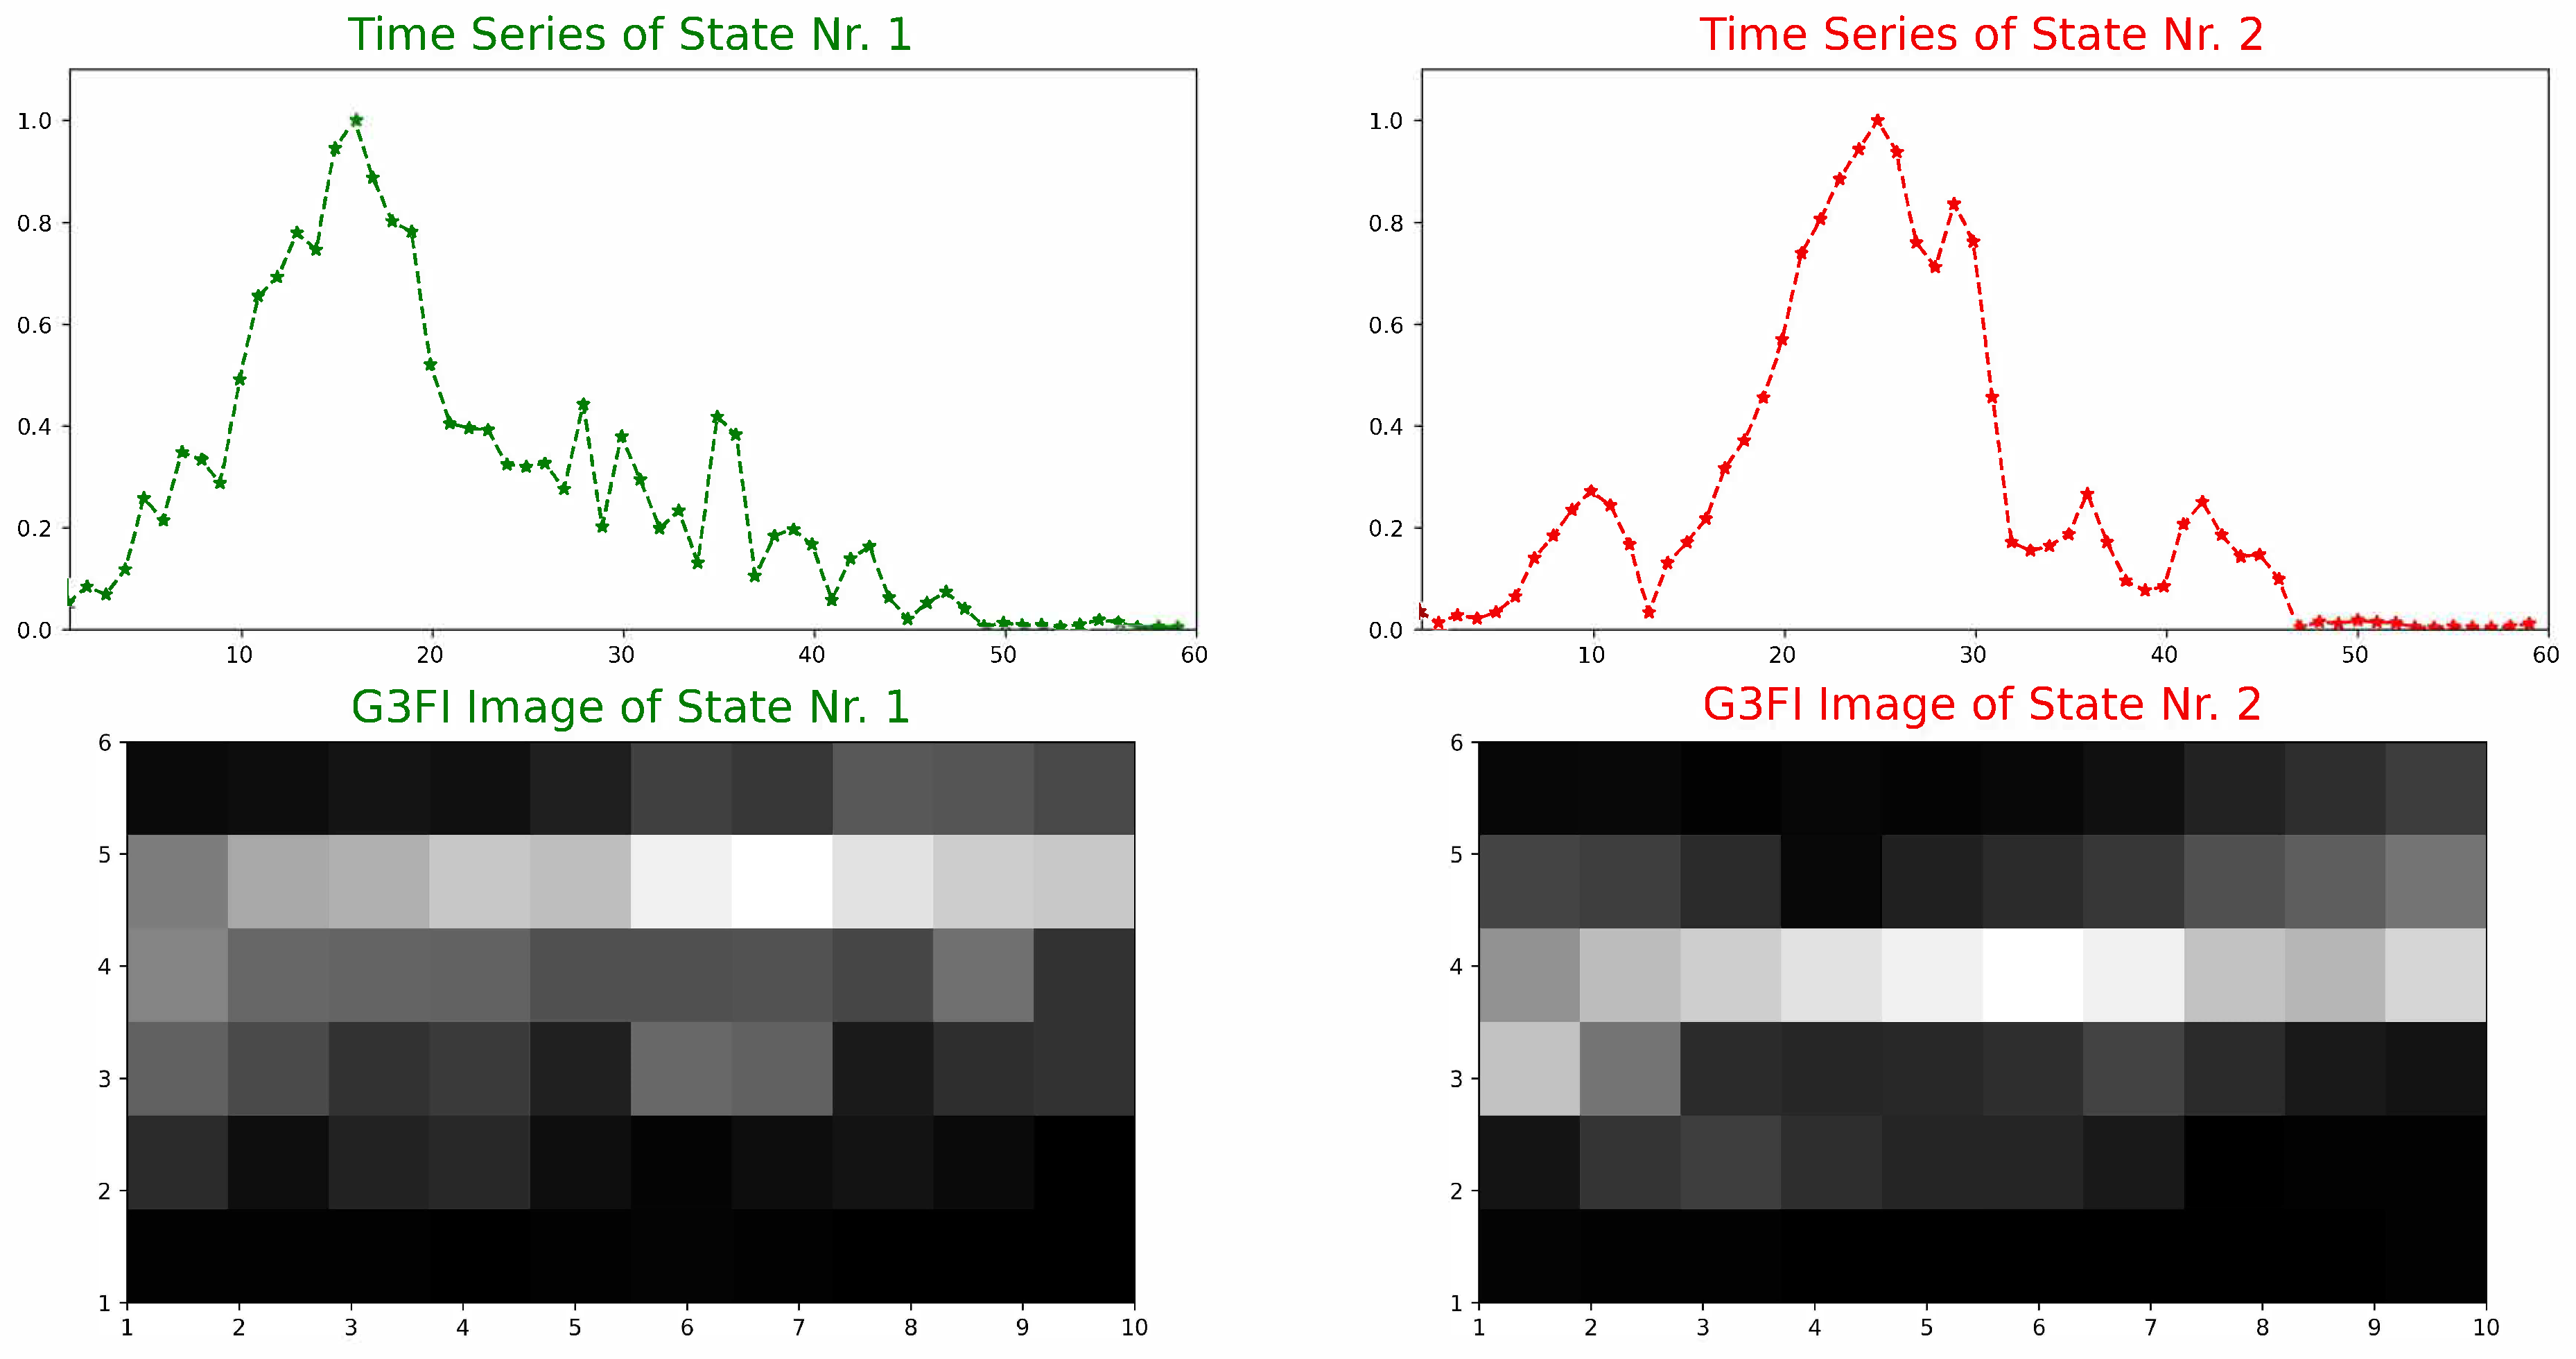
The term “fingerprint” is used in the context of this novel G3FI technique to indicate that each state that can be classified and distinguished with the time series dataset has a specific G3FI image(s) with its grayscale distribution, which could be called a fingerprint, as illustrated in Figure 13. As shown in this figure, the original time series has two states (e.g., state 1: rock; state 2: mine in the sonar dataset). The behavior of the signal of each state can be distinguished based on the peaks, their position, and their number. Related G3FI images reacted to this behavior in terms of their gray-level distribution. This distribution can be understood as the fingerprint for each state.
Figure 13.
“Fingerprint” in the context of the G3FI technique: original time series of the two states (top); related G3FI images (bottom).
Reshaping the G3FI matrix using Formula (11) will not result in sparsity because grayscaling and normalizing to the [0, 255] range depends on multiple variable values for each sample/row of the time series dataset. These values generally cannot all be zero. Furthermore, the transformation in Formula (10) depends on the maximum and minimum values in the range, not its length. Additionally, the G3FI image’s dimensions are two-dimensional, regardless of the length or number of multivariate variables in the sample time series. Like state-of-the-art imaging time series techniques, the G3FI technique addresses local features of the considered multivariate time series dataset, i.e., the sample or row. Therefore, loss of these features will be avoided.
Temporal features play a significant role in feature engineering, which involves additional feature extraction methods. However, this role is not considered when implementing the CNN model as a classifier because feature engineering is embedded within the DL/CNN model. The periodic features of the multivariate time series dataset will be preserved because G3FI technology considers the original order and adjacency when creating the descriptive feature vector for each sample. These periodic features will be present in the same pixel in all G3FI images, which will be equal in number to the samples/rows in the multivariate time series dataset. Since the feature extractor employs the principles of convolution and pooling in CNNs, these periodic features will be extractable and trackable when the related feature maps of the CNN model are generated.
3.2. Comparison of Images of State-of-the-Art and Novel G3FI Techniques
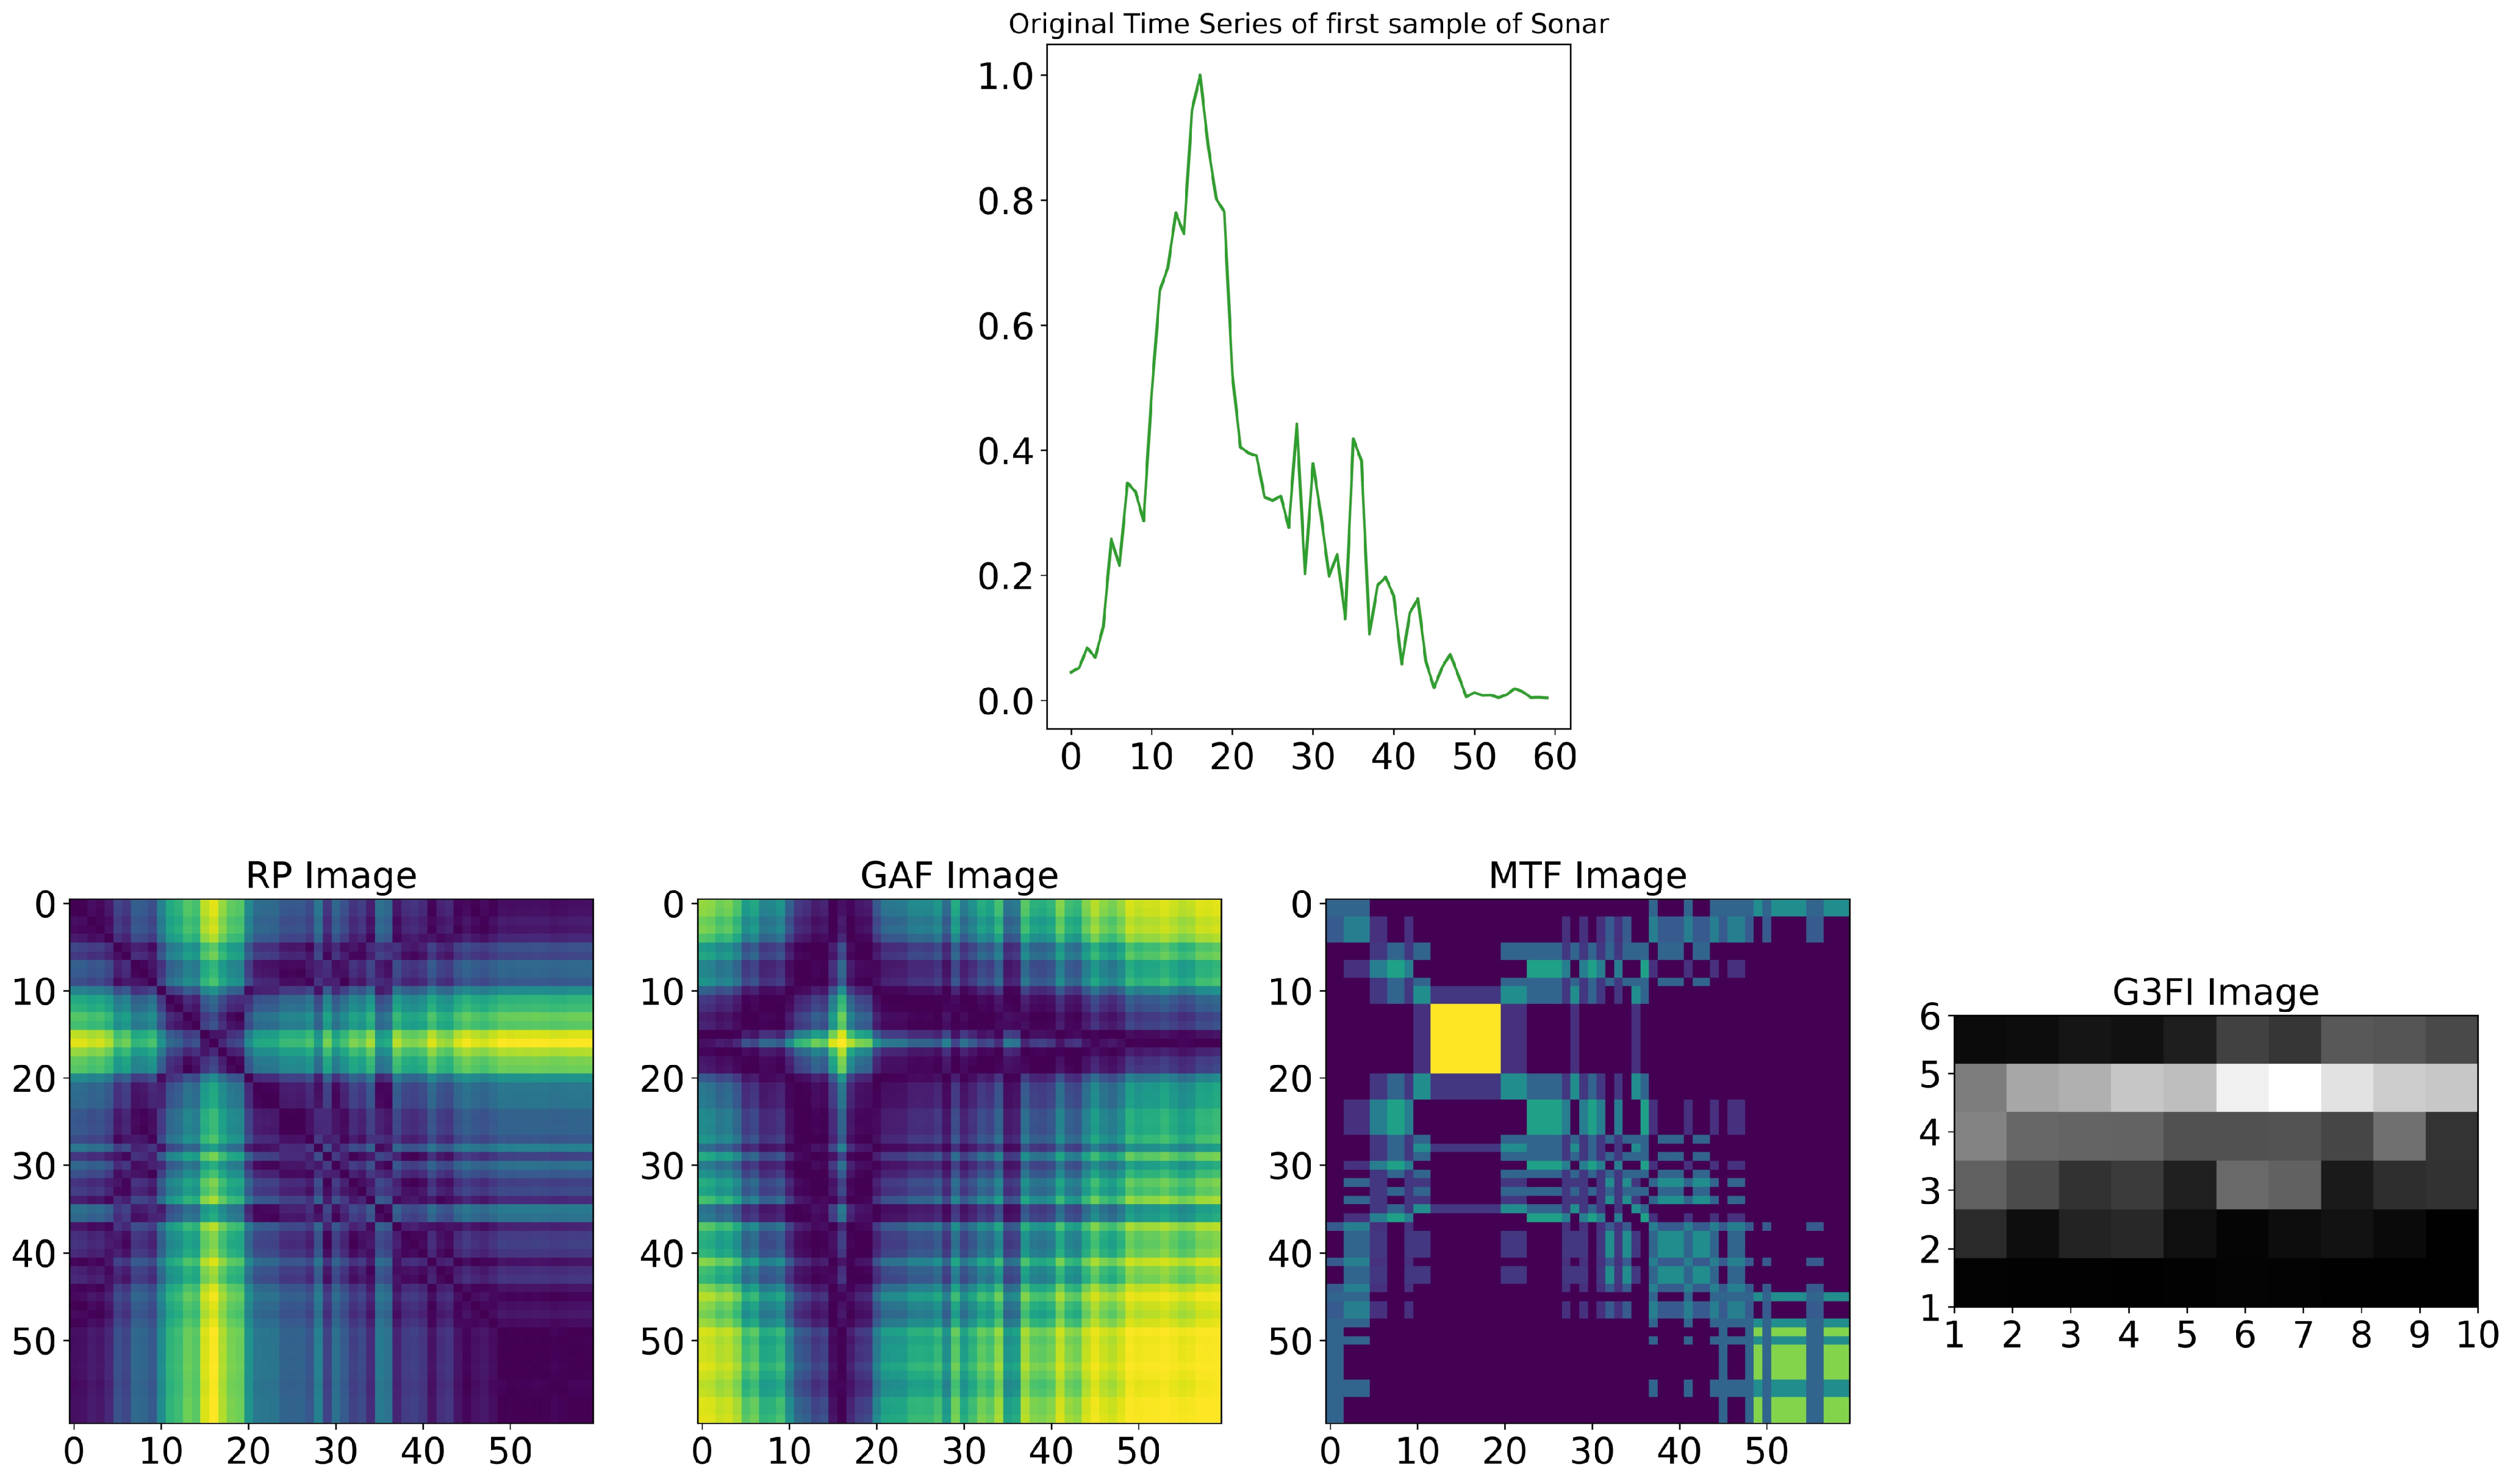
Figure 14 shows the results of the state-of-the-art methods (RP, GAF, and MTF) and the new G3FI techniques applied to time series with 60 descriptive features. It can be observed that the aforementioned issues with state-of-the-art images, such as diagonal symmetry and extremely high resolution (where 3600 pixels correspond to ), are addressed with the G3FI technique. This is evidenced by the fact that the associated pixels of this image represent only each descriptive feature, and the image possesses a resolution of 60 pixels. The images of the three state-of-the-art techniques for imaging time series in Figure 14 were created using the functions RecurrencePlot, GramianAngularField, and MarkovTransitionField of The PYTS (Python Package for Time Series Classification) based on their default values as the hyperparameters: [image size: 60; scaling range: , method: “summation“] for GAF, [image_size: 60; time_delay: 1; threshold: None] for RP, and [image_size: 60; n_bins: 5] for MTF. The image size was set to 60 because the length of the time series of each sample is 60 variables [23].
Figure 14.
Results of time series imaging: original time series consisting of 60 descriptive features/variables (top); related transformed images of the RP, GAF, and MTF and G3FI techniques (bottom).
3.3. CNN Classification System Based on G3FI Image-Encoded Time Series
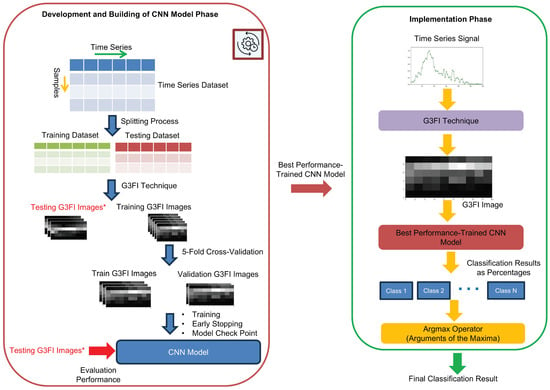
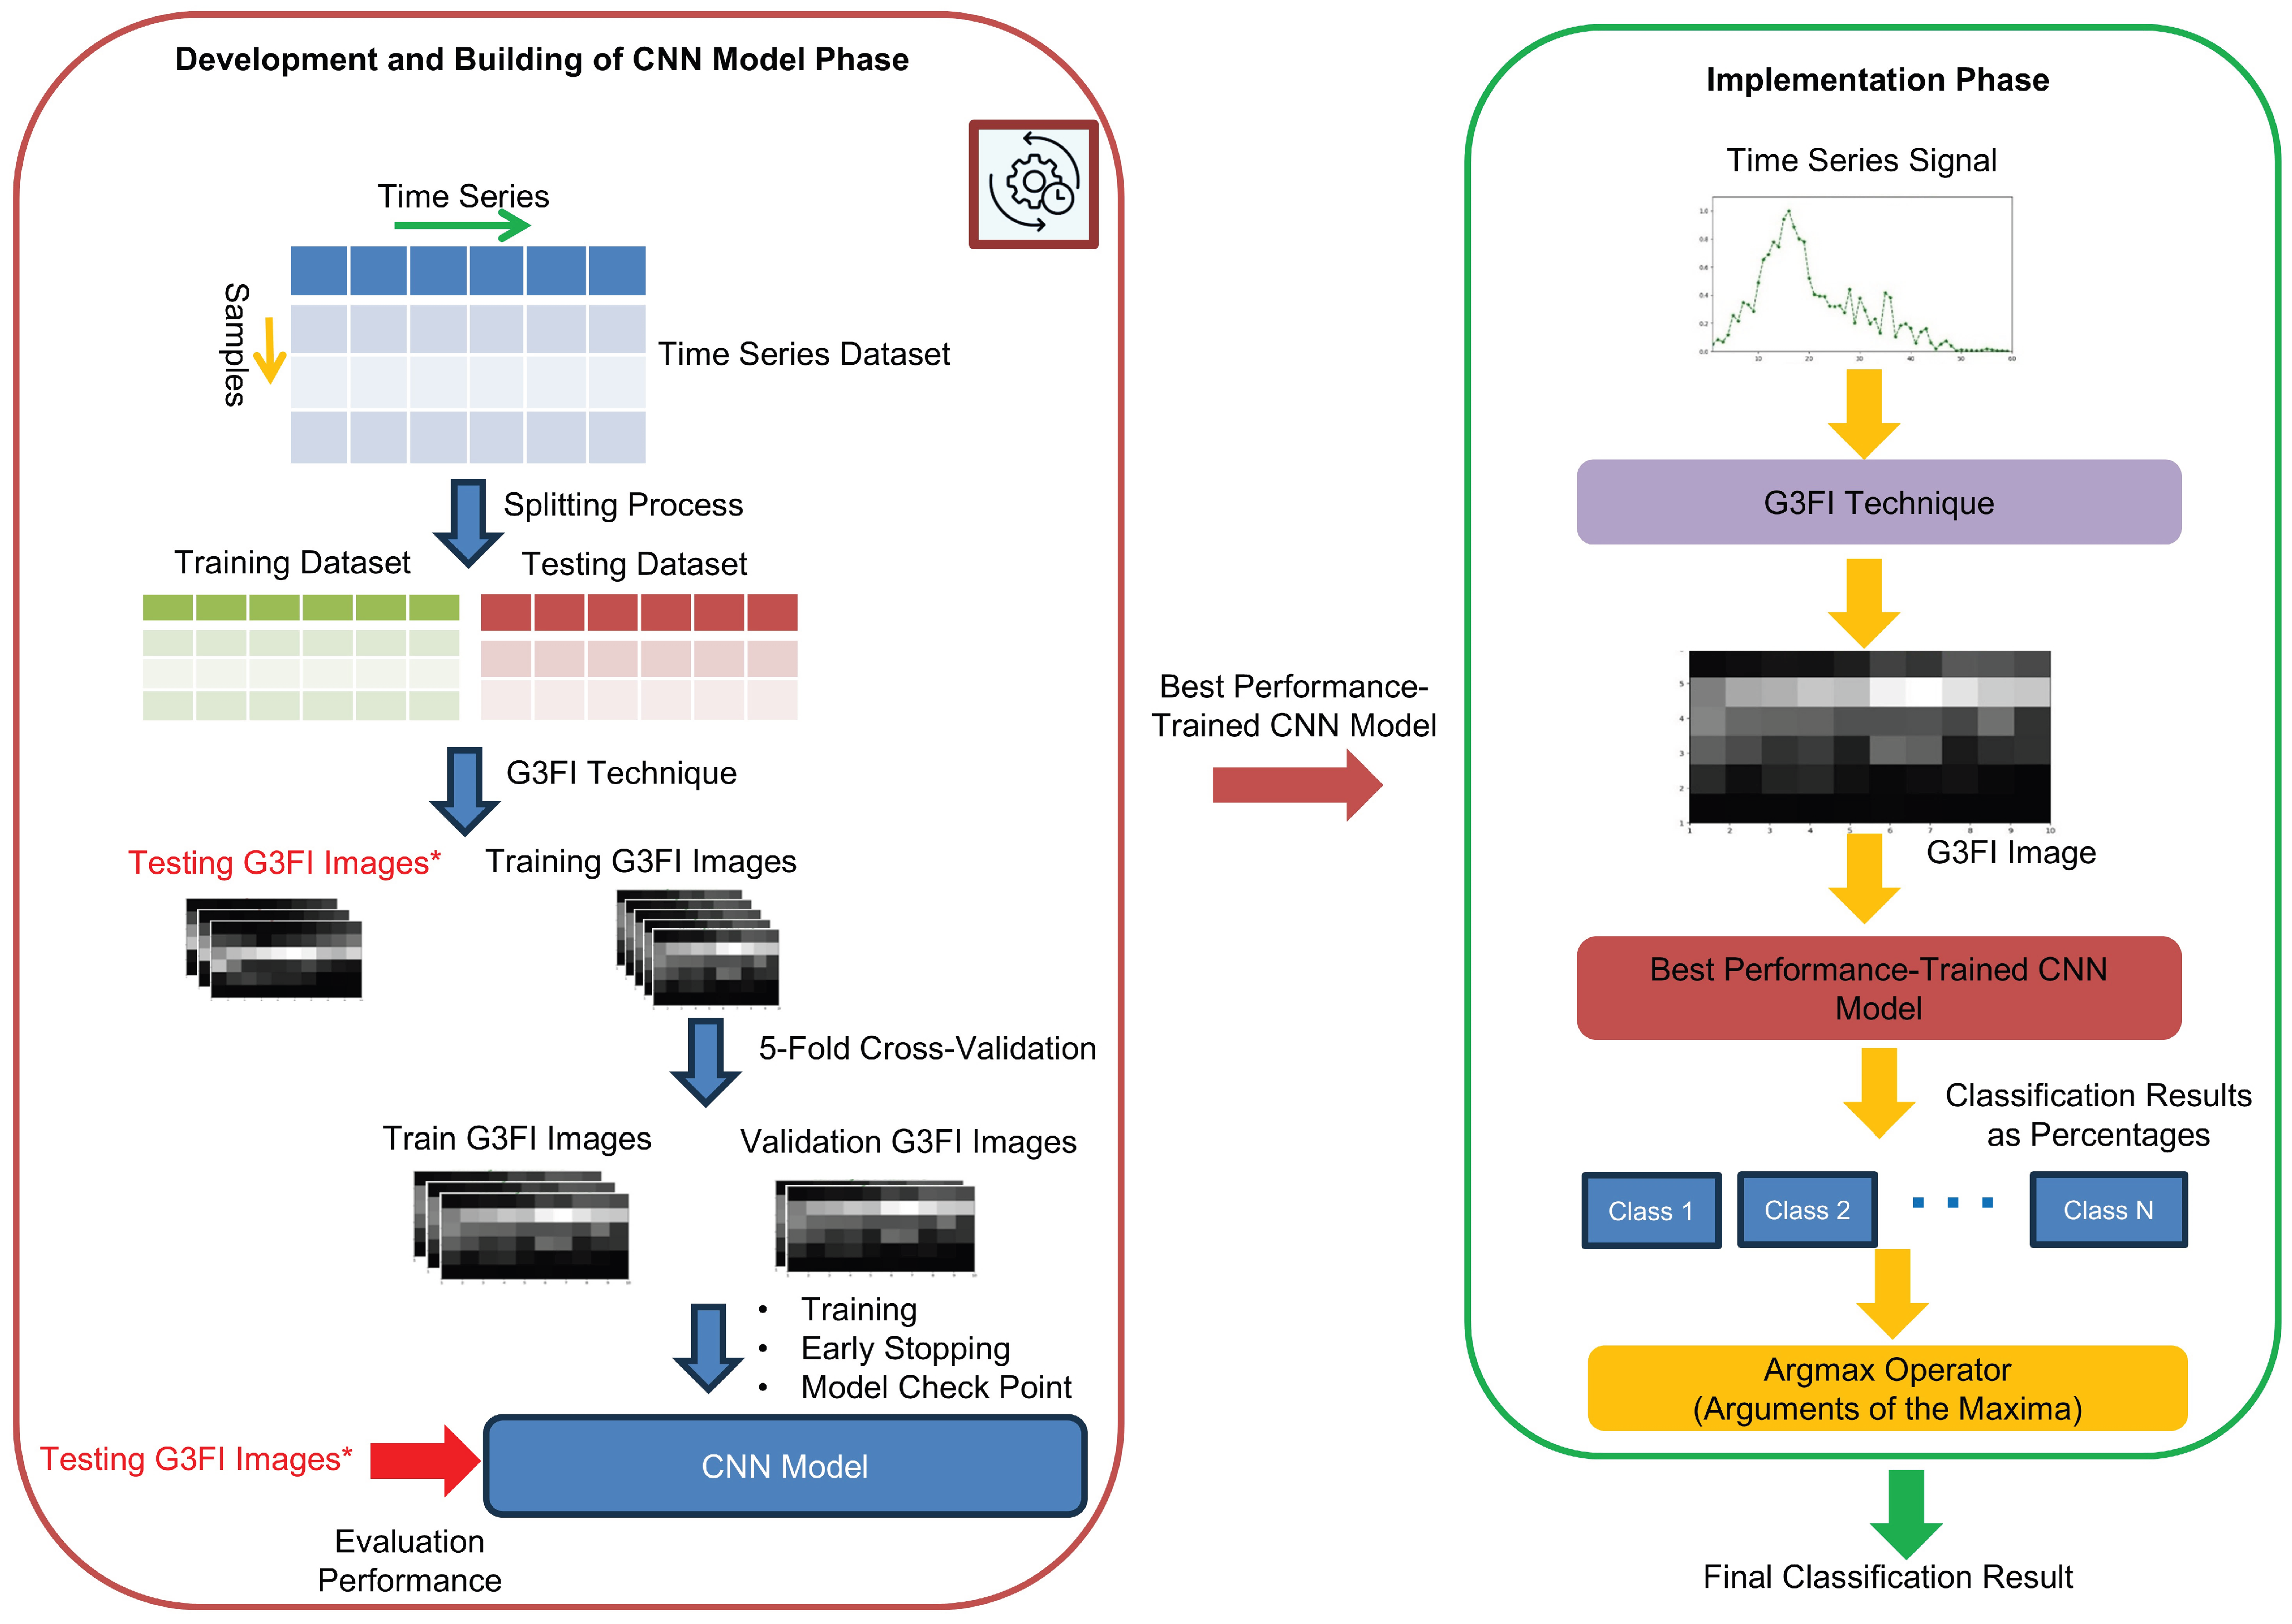
The architecture of the proposed classification system for the time series encoded using the G3FI technique is shown in Figure 15. It starts by dividing the considered time series dataset into a training dataset and a test dataset. The developed G3FI time series technique is applied to the training and test dataset to generate the corresponding G3FI images. The training G3FI images are split into a training dataset and a validation dataset with five folds using the cross-validation technique. The training dataset with G3FI images is used to train the CNN model. The validation dataset with G3FI images is used to prevent overfitting during the modeling process by employing the early stopping technique (the EarlyStopping function in Keras). The validation dataset is used to store the best modeling results using the model checkpoint technique (the ModelCheckpoint function in Keras). The test dataset is used to evaluate the best model and decide whether to keep the final trained CNN model. All previous steps are included in the development and building phases of the CNN model.
Figure 15.
Architecture of the proposed classification system for time series encoded using the G3FI technique.
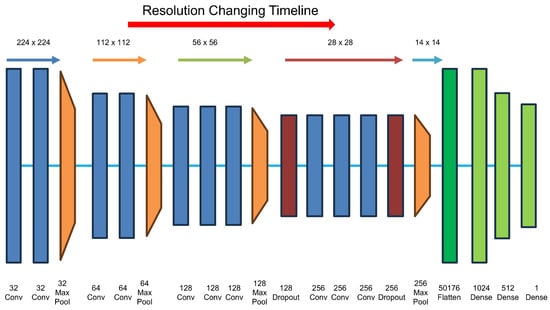
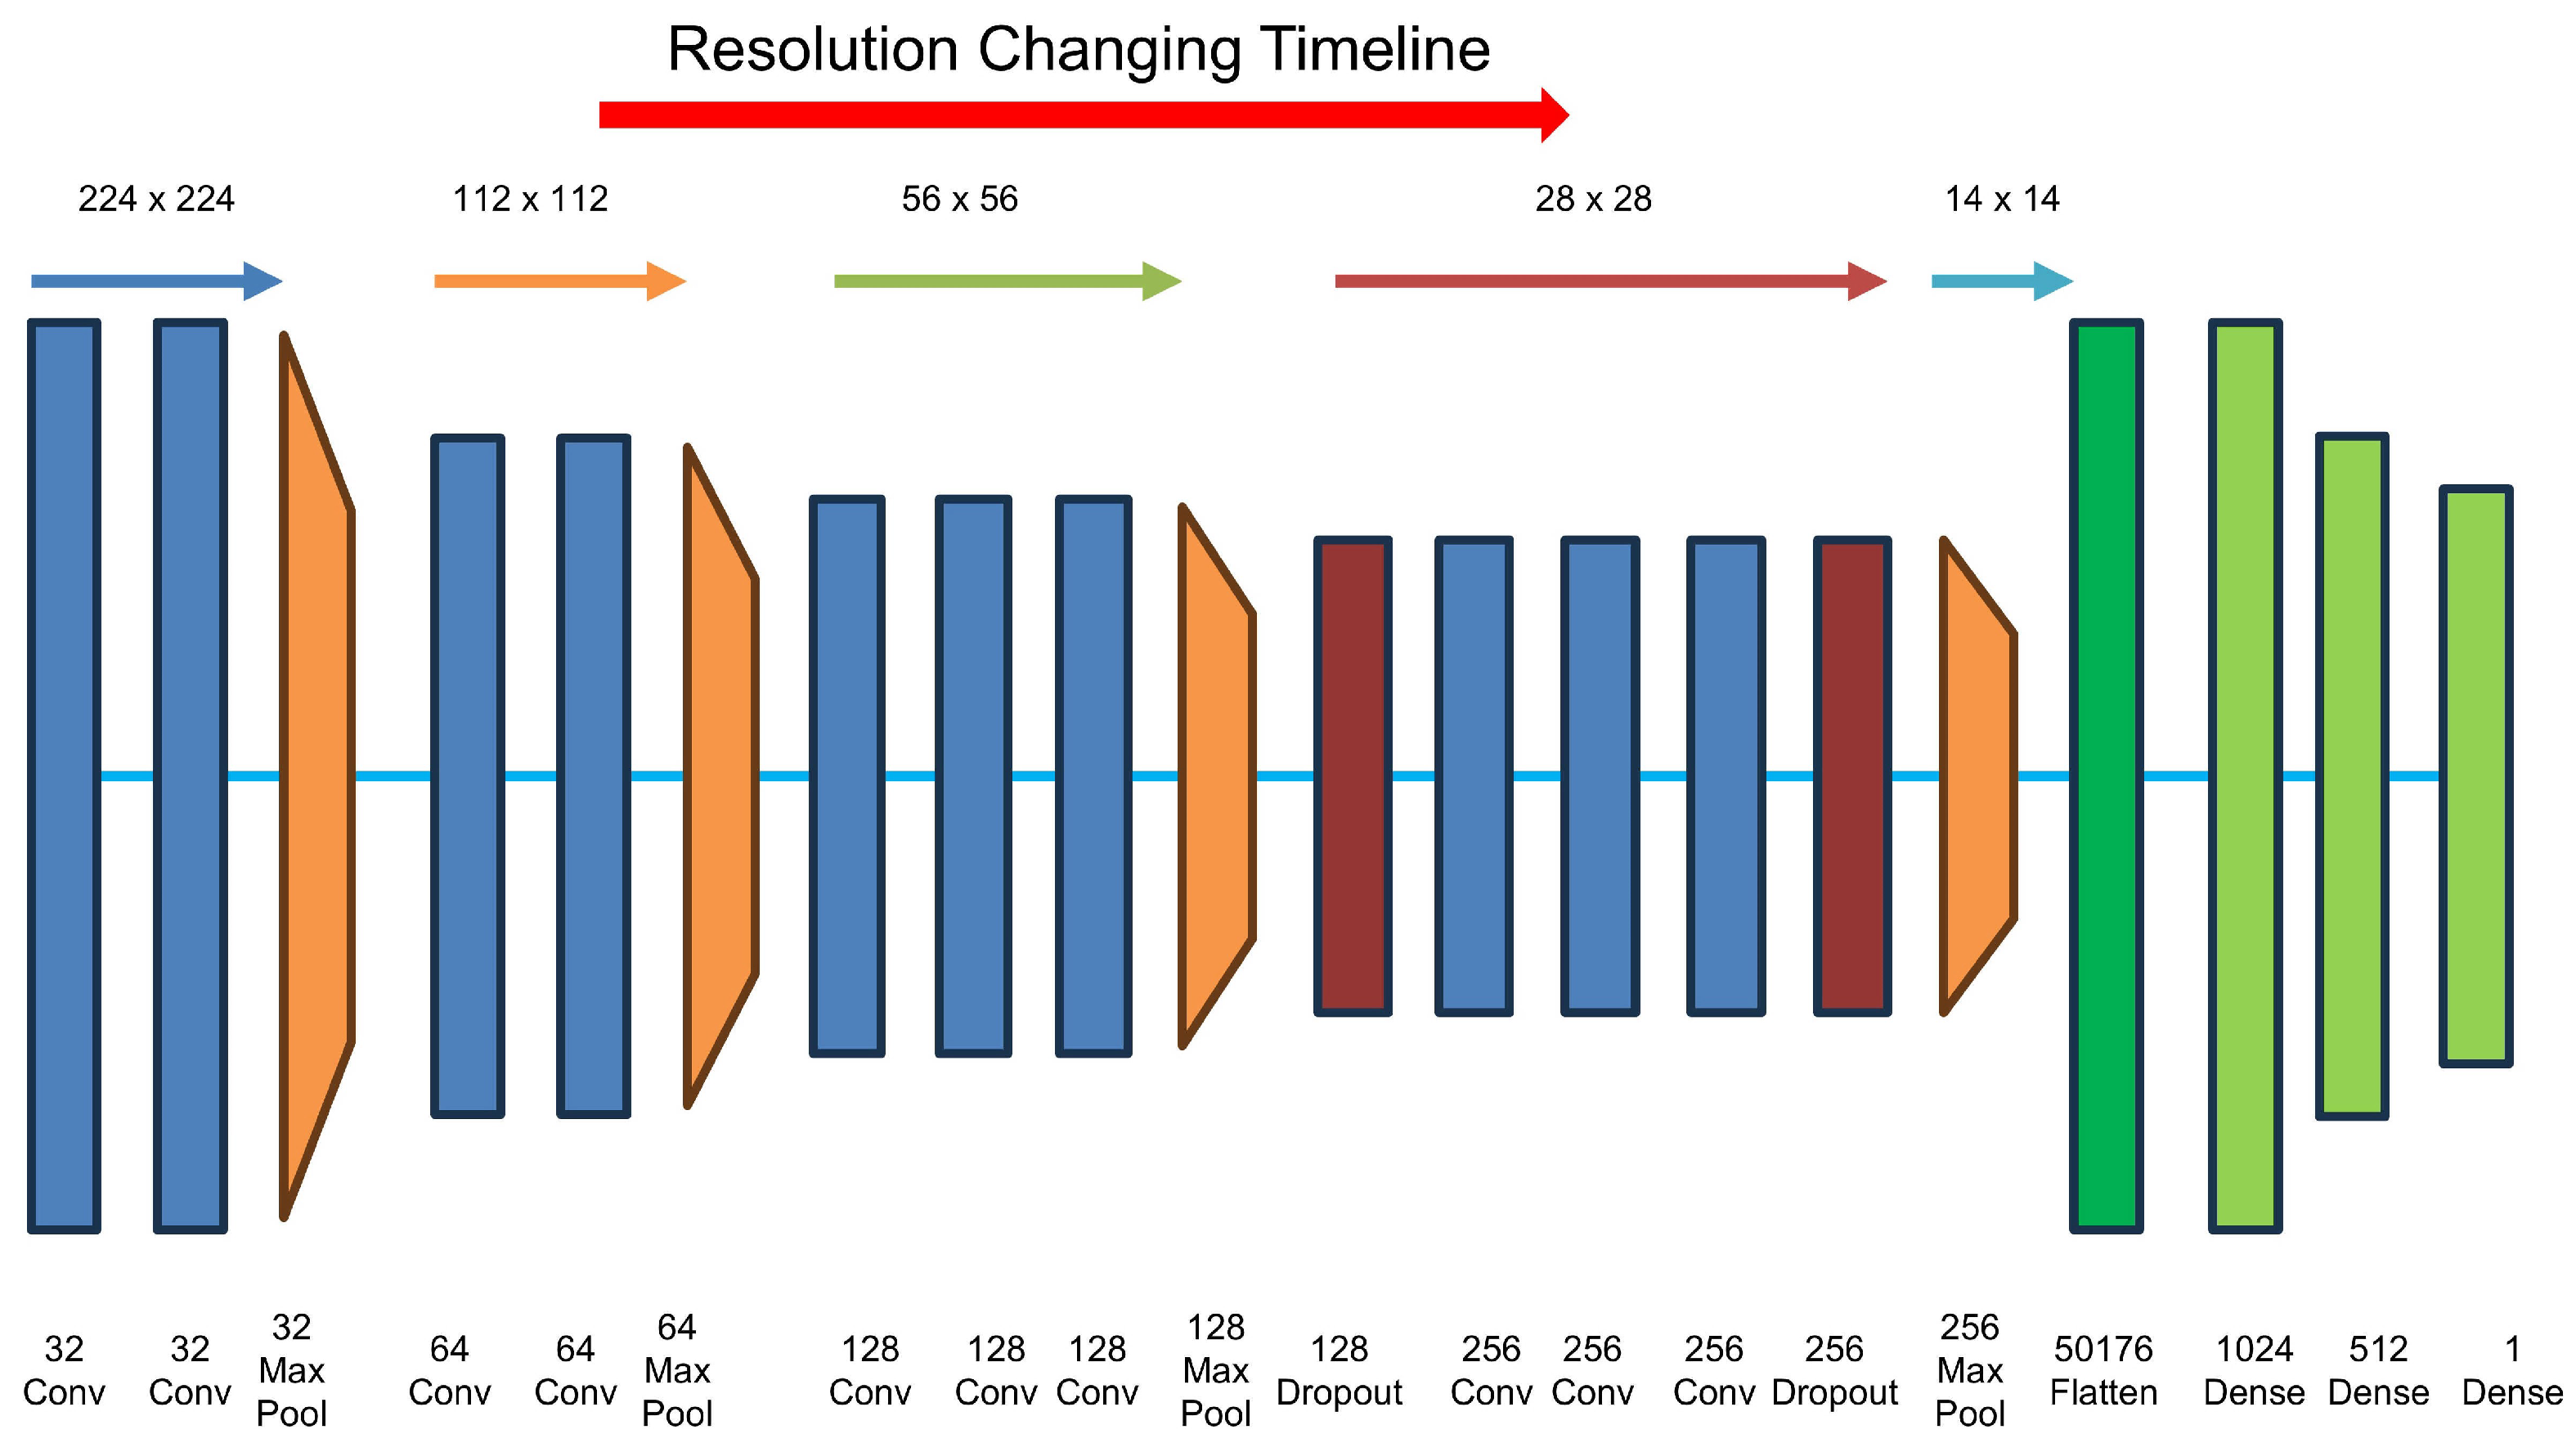
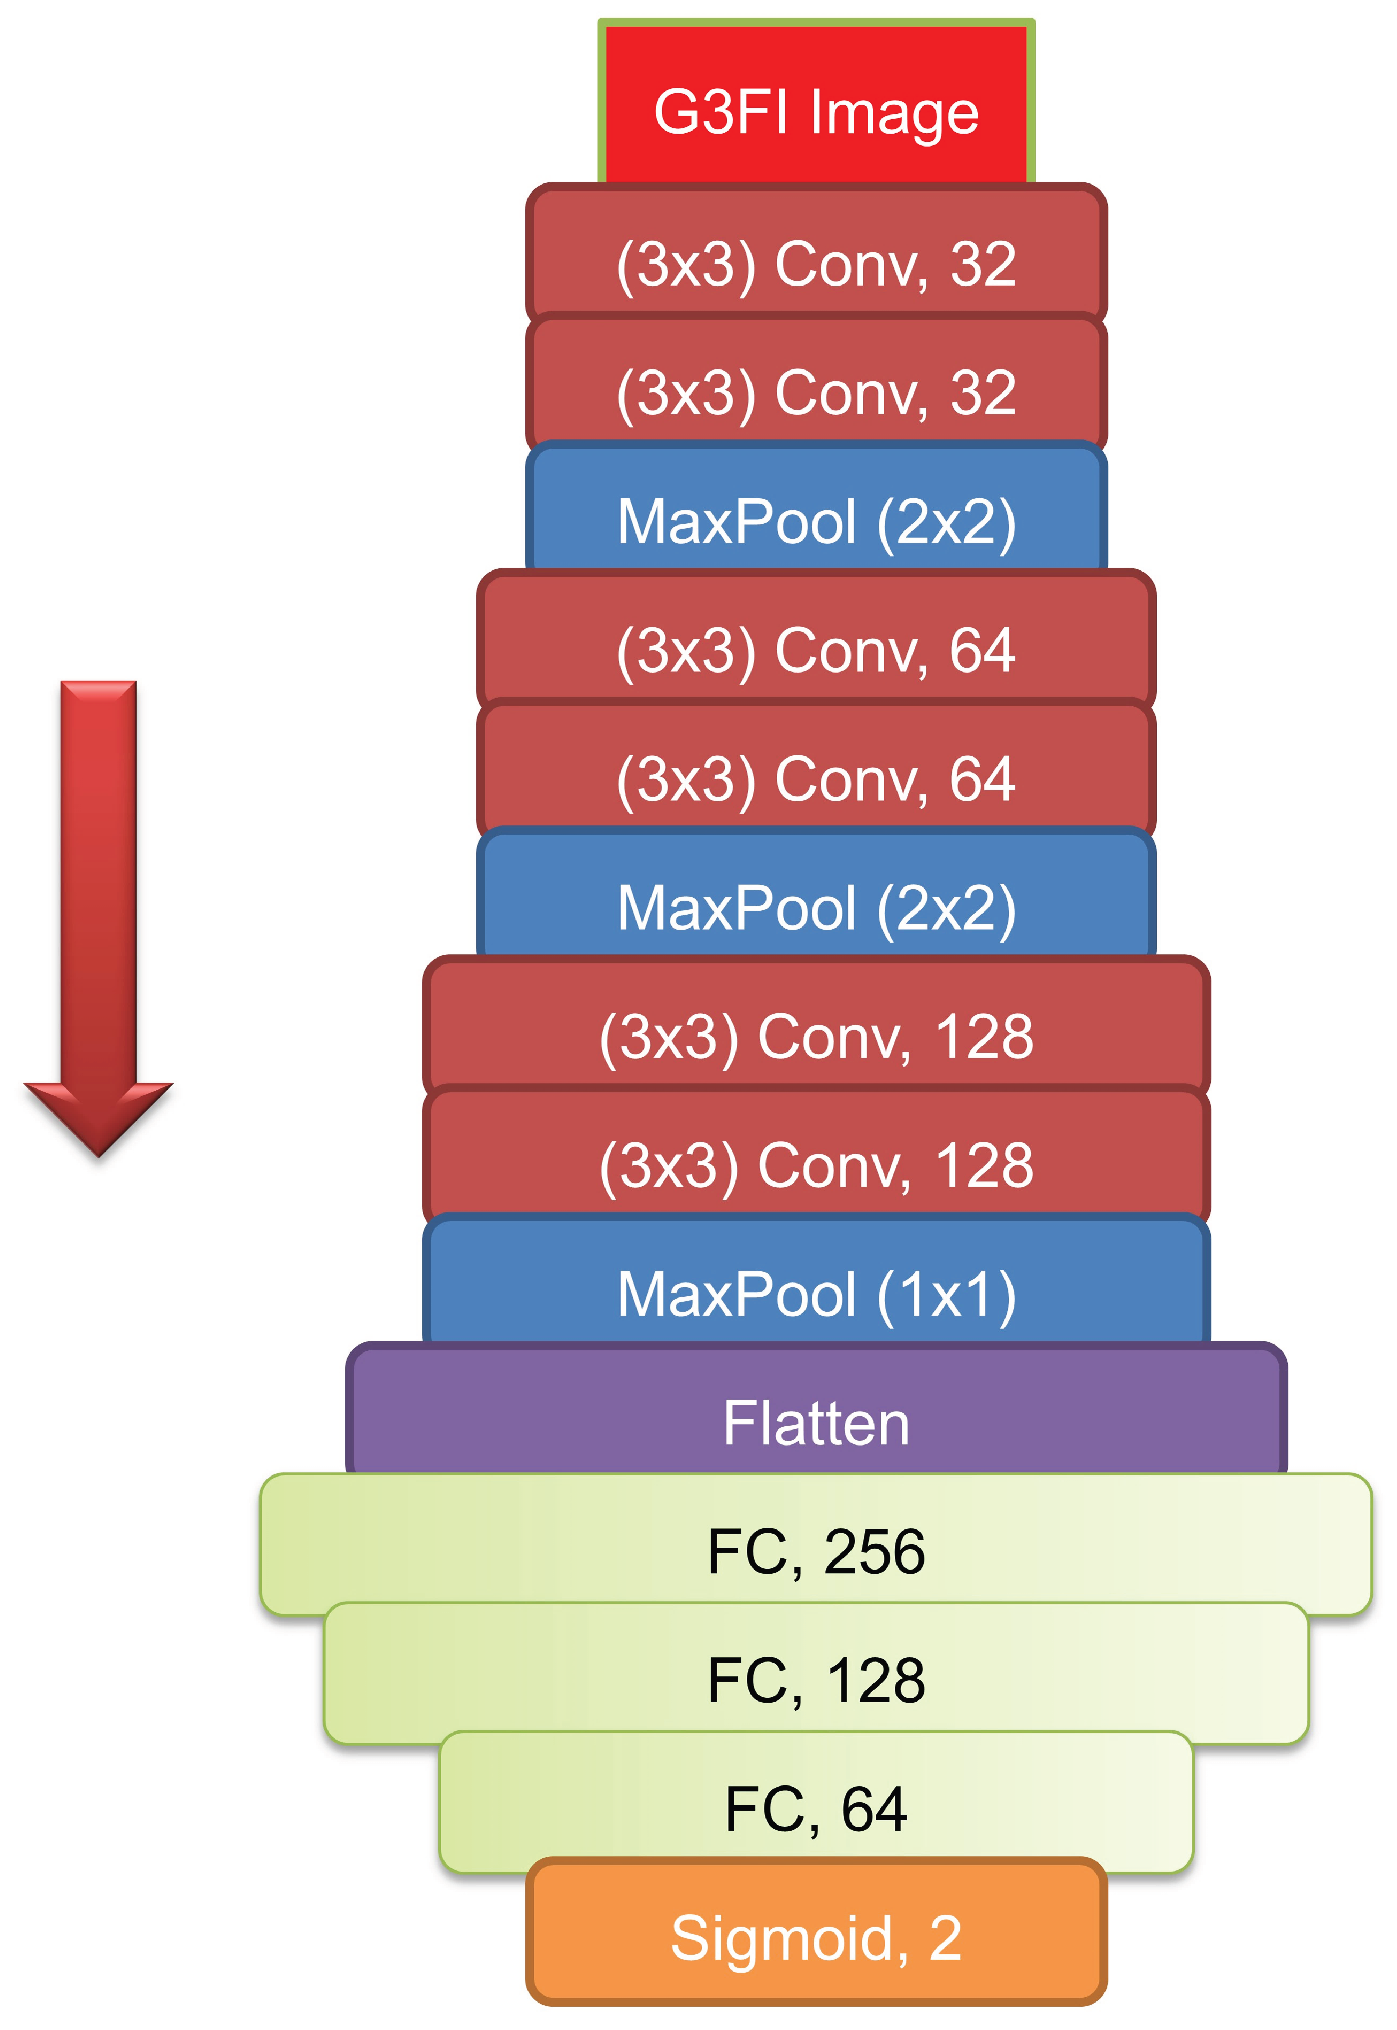
During the implementation phase of the CNN model, the unknown time series signal will be converted into a G3FI image. The final classification results are obtained by predicting this image with the fully trained CNN model. The structure of the CNN model used in the proposed G3FI image-encoded time series CNN-based classification system consists of stacked layers, as shown in Figure 16.
Figure 16.
Structure of the CNN model used in the proposed G3FI-Image-Encoded-Time-Series-CNN-based Classification System. Legend: Conv—Convolutional Layer with a filter size of , MaxPool—Maximum Pooling Layer with a window size , Flatten— Flattening Layer, FC—Fully Connected Layer, Sigmoid—Sigmoid Output Layer.
The following components are utilized in the construction of the proposed CNN model:
- ReLU is incorporated as the activation function in all applied layers.
- The batch normalization (BN) technique is implemented prior to the ReLU activation function of the convolutional layers. This is intended to avoid the phenomenon of vanishing gradients and to speed up model training.
- The training parameters are:
- –
- “Same” for padding
- –
- “He uniform variance scaling initializer” for the weight initializer
- –
- “Gradient descent” with a learning rate of 0.01 and a momentum of 0.9 for the optimizer
- –
- “Binary cross entropy” for the loss function
- –
- “Accuracy” for the evaluation metric
- –
- “Early stopping” with a monitor of “validation loss,” a mode of “min,” and a patience of 3
- –
- “Model checkpoint” with a monitor of “validation accuracy,” a mode of “max,”
- –
- 30 epochs, and batch size of 32.
Following the training of the G3FI-CNN model, the total number of parameters for each dataset considered is presented in Table 2.
Table 2.
Overview of the total number of parameters of the trained G3FI-CNN model proposed in this study.
4. Results and Discussion
In order to generate the G3FI images of the time series datasets (Computers, AbnormalHeartbeat, DodgerLoopGame, ECG200, and Sonar) and build the proposed classification system (Figure 16), the following libraries and packages were run on a “13th Gen Intel(R) Core(TM) i5-1345U 1.60 GHz” GPU with 16 GB of memory: (1) Anaconda 2.5.0, (2) Python 3.9.18, (3) Keras 2.14.0, (4) Numpy 1.24.3, (5) Scikit-Learn 1.1.3, and (6) Pandas 2.1.1.
Table 3 shows best classification performance of the two state-of-the-art image-coded time series-based CNN classification systems from related works and the proposed G3FI image-encoded time series-based CNN classification system.
Table 3.
Performance comparison of the G3FI image-encoded time series CNN-based classification system with systems in related work.
In the context of the related work by Gross et al. [1], the best transfer learning strategy employed the VGG16 architecture as a CNN-based classification model running on a GPU for the considered time series data, and the best performance for each dataset is shown in the first column of Table 3. This table shows that the G3FI-CNN-based classification model, running on a CPU, compared to the VGG16 classification model used in [1], led to
- Comparative results for the Computer and DodgerLoopGame datasets;
- Superior results for the ECG200 and AbnormalHeartbeat datasets.
The inconsistent performance of GAF technology when classifying the four multivariate time series benchmark datasets suggests that the “Computers” and “DodgerLoopGame” datasets exhibit stronger periodic and quasi-periodic properties than the “ECG200” and “AbnormalHeartbeat” datasets. Consequently, the “aliasing” phenomenon has a stronger effect on generating GAF images for the first two datasets than for the second two. In GAF, aliasing occurs when two distinct time series produce identical images due to the non-uniqueness of mapping time series values to polar coordinates using trigonometric functions, such as the cosine function. This information loss limits the invertibility of GAF and can cause confusion in downstream tasks, such as image classification, because two different time series may map to the same visual image. Therefore, G3FI technology is more robust and stable than GAF technology in terms of periodicity and strength during image generation. The superiority of the GAF-CNN combination over the G3FI-CNN combination for the “Computers” and “DodgerLoopGame” datasets is due to the fact that the VGG16 architecture is more complex and larger than the G3FI-CNN-based classification model.
The VGG16 architecture has a total of 14,788,673 parameters for the trained CNN model. The highest total number of parameters of the G3FI-CNN model is 5,866,658, in the case of the AbnormalHeartbeat dataset, and the lowest number of trained parameters is 525,474 in the case of the “ECG200” dataset. Comparing the total number of parameters of the VGG16 model to the highest and lowest numbers of parameters of the G3FI-CNN model shows that the complexity of the proposed G3FI-CNN model is less than one third of the complexity of the VGG16 model needed to achieve the best, and comparable, results. This is because the VGG16 architecture requires an image with a fixed size ( pixels) as input, regardless of the original size of the processed image; therefore, the total number of parameters of the trained VGG16 model is fixed each time. Conversely, the required size of the input image of the G3FI-CNN model uses the original size of the G3FI image; therefore, the total number of parameters of the trained model varies each time depending on the length/number of descriptive features of the considered time series.
With respect to the CNN-based classification used in [20], it can be noted that the associated image of the sonar time series dataset was generated by fusing GASF, RP, and MTF images to create an RGB image consisting of three channels as input for the presented classification system. Moreover, due to the structure of the proposed method, the total number of parameters of the trained CNN model could be estimated to be about 5M (the actual value of this number was not mentioned in the corresponding paper). Despite the complexity of the image input and the CNN-based classification model, the optimal performance achieved was 97.6%. As illustrated in Table 3, the G3FI-CNN-based classification model with a single-channel image input and a total of 394,402 parameters (i.e., the number of parameters of the trained model) exhibits a related performance of 98.5%. In consideration of the results and associated discourse, it is evident that the G3FI-CNN-based classification exhibits simplicity, robustness, and innovation with regard to the imaging time series technique, specifically G3FI.
5. Conclusions and Future Work
The transformation of time series into images represents a novel concept of significant interest within the research community. This is because such techniques enable the application of the remarkable and advanced achievements and developments of CNNs in DL and CV to time series datasets. We determined that state-of-the-art transformation techniques such as RP, GASF/GADF, and MTF exhibit significant disadvantages: (1) The complexity of the transformation processes is very high. (2) The resulting image contains redundant and duplicate information due to its diagonally symmetric structure. (3) The resolution of this image is the square of the number of descriptive features of the considered time series data. Consequently, the greater the number of these features, the higher the resolution of this image. (4) Therefore, the time required to process this image to achieve the desired goals, such as classification, is very high.
We then put forth a novel and robust imaging time series technique, G3FI, as a significant contribution to imaging time series research and implementation. This technique avoids the drawbacks of the stat-of-the-art techniques by employing a two-step transformation process to transfer the descriptive features/variables of each sample in the time series to a 2D image. The resulting image possesses a non-symmetric property, and its resolution is equivalent to the number of descriptive features/variables of the transformed sample because it uses only a two-step transformation process to transfer the descriptive features/variables of each sample of the time series into the 2D image, and the resulting image has a non-symmetric property and its resolution is equal to the number of descriptive features/variables of the transformed sample. To prove the concept of G3FI, the proposed CNN system was built for the classification of five time series datasets transferred into images using the G3FI technique and compared with the image-encoded CNN-based classification systems proposed in related work.
The results of the presented proof of concept show that G3FI and the associated CNN-based classification system are capable of handling time series tasks and are comparatively successful. The analysis and investigation of the presented CNN as a DL system for imaging time series datasets in related works can reveal that achieving the best performance will be more or less associated with the complexity in terms of the images obtained using the state-of-the-art imaging time series techniques, as well as that of the CNN model (either through the use of pre-trained CNN models/transfer learning or by increasing the hidden layers of the CNN models to be developed from scratch). These requirements could be avoided using the developed G3FI-CNN-based system because of the simplicity and robustness of the G3FI imaging time series technique and the CNN model’s structure.
Future work on this contribution could include the following:
- Investigating and analyzing the effect of the “K” and “L” parameters on the CNN model’s performance.
- Implementing a feature selection technique to identify the most relevant features before the imaging process.
- Application of the G3FI-CNN approach to multivariate time series datasets and evaluation using accuracy, recall, precision, and F1-score metrics.
- Identify the “K” and “L” parameters using machine learning regression tasks based on the dimensions of the multivariate time series dataset in question. This version implemented a mathematical calculation method to maximize the G3FI image square in the identification process.
- Application of other mainstream deep learning architectures besides the CNN structure as the classifier.
Author Contributions
Conceptualization, H.A.J. and M.J.; methodology, H.A.J. and M.J.; software, H.A.J.; writing—original draft preparation, H.A.J. and M.J.; sketches and pictures, H.A.J. and M.J.; writing—review and editing, H.A.J., M.J. and L.A.-S.; manuscript revisions, H.A.J., M.J. and L.A.-S.; supervision, M.J. and L.A.-S.; project administration, M.J. and L.A.-S.; funding acquisition, M.J. and L.A.-S. All authors have read and agreed to the published version of the manuscript.
Funding
This research was partly funded by the Central Innovation Programme for small- and medium-sized enterprises (SMEs) of the German Federal Ministry for Economic Affairs and Climate Action, grant number 16KN120120.
Data Availability Statement
All of the datasets considered in this paper are publicly available.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Gross, J.; Baumgartl, R.; Hermann, B. Benchmarking Transfer Learning Strategies in Time-Series Imaging: Recommendations for Analyzing Raw Sensor Data. IEEE Access 2022, 10, 16977–16991. [Google Scholar] [CrossRef] [Scilit]
- Ferencz, K.; Domokos, J.; Kovács, L. Analysis of time series data for anomaly detection. In Proceedings of the 2022 IEEE 22nd International Symposium on Computational Intelligence and Informatics and 8th IEEE International Conference on Recent Achievements in Mechatronics, Automation, Computer Science and Robotics (CINTI-MACRo), Budapest, Hungary, 21–22 November 2022. [Google Scholar] [CrossRef] [Scilit]
- Jantawong, P.; Hnoohom, N.; Jitpattanakul, A.; Mekruksavanich, S. Time Series Classification Using Deep Learning for HAR Based on Smart Wearable Sensors. In Proceedings of the 26th International Computer Science and Engineering Conference (ICSEC), Sakon Nakhon, Thailand, 21–23 December 2022. [Google Scholar] [CrossRef] [Scilit]
- Fu, T. A review on time series data mining. Eng. Appl. Artif. Intell. 2011, 24, 164–181. [Google Scholar] [CrossRef] [Scilit]
- Bottou, L. From machine learning to machine reasoning. Mach. Learn. 2011, 94, 133–149. [Google Scholar] [CrossRef] [Scilit]
- Artemios-Anargyros, S.; Evangelos, S.; Vassilios, A. Image-based time series forecasting: A deep convolutional neural network approach. Neural Netw. 2023, 157, 39–53. [Google Scholar] [CrossRef] [Scilit]
- Sarker, I.H. AI-Based Modeling: Techniques, Applications and Research Issues Towards Automation, Intelligent and Smart Systems. SN Comput. Sci. 2022, 3, 158. [Google Scholar] [CrossRef] [Scilit]
- Zhong, Z.; Li, J.; Luo, Z.; Chapman, M. Spectral-spatial residual networks for hyperspectral image classification: A 3-D deep learning framework. IEEE Trans. Geosci. Remote Sens. 2018, 56, 847–858. [Google Scholar] [CrossRef] [Scilit]
- Silberzahn, R.; Uhlmann, E.L.; Martin, D.P.; Anselmi, P.; Aust, F.; Awtrey, E.; Bahník, S.; Bai, F.; Bannard, C.; Bonnier, E.; et al. Many analysts, one data set: Making transparent how variations in analytic choices affect results. Adv. Methods Pract. Psychol. Sci. 2018, 1, 337–356. [Google Scholar] [CrossRef] [Scilit]
- Rawat, T.; Khemchandani, V. Feature engineering (FE) tools and techniques for better classification performance. Int. J. Innov. Eng. Technol. (IJIET) 2017, 8, 169–179. [Google Scholar] [CrossRef] [Scilit]
- Schmidt, J.; Marques, M.R.G.; Botti, S.; Marques, M.A.L. Recent advances and applications of machine learning in solid-state materials science. Npj Comput. Mater. 2019, 5, 83. [Google Scholar] [CrossRef] [Scilit]
- Janssens, O.; Slavkovikj, V.; Vervisch, B.; Stockman, K.; Loccuer, M.; Verstockt, S.; Van de Walle, R.; Van Hoecke, S. Convolutional Neural Network Based Fault Detection for Rotating Machinery. J. Sound Vib. 2016, 377, 331–345. [Google Scholar] [CrossRef] [Scilit]
- Schmitz-Valckenberg, S.; Göbel, A.P.; Saur, S.; Steinberg, J.; Thiele, S.; Wojek, C.; Russmann, C.; Holz, F.G. Automated retinal image analysis for evaluation of focal hyperpigmentary changes in intermediate age-related macular degeneration. Transl. Vis. Sci. Technol. 2016, 5, 3. [Google Scholar] [CrossRef] [Scilit]
- Fawaz, H.I.; Forestier, G.; Weber, J.; Idoumghar, L.; Müller, P.A. Deep learning for time series classification: A review. Data Min. Knowl. Discov. 2019, 33, 917–963. [Google Scholar] [CrossRef] [Scilit]
- LeCun, Y.; Bengio, Y.; Hinton, G. Deep learning. Nature 2015, 512, 436–444. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Tang, Y.; Blincoe, K.; Kempa-Liehr, A.W. Enriching feature engineering for short text samples by language time series analysis. EPJ Data Sci. 2020, 9, 26. [Google Scholar] [CrossRef] [Scilit]
- Smyl, S. A hybrid method of exponential smoothing and recurrent neural networks for time series forecasting. Int. J. Forecast. 2020, 36, 75–85. [Google Scholar] [CrossRef] [Scilit]
- Wang, Z.; Oates, T. Encoding Time Series as Images for Visual Inspection and Classification Using Tiled Convolutional Neural Networks. In Proceedings of the Workshops at the 29th AAAI Conference on Artificial Intelligence, Austin, TX, USA, 25–30 January 2015. [Google Scholar]
- Hatami, N.; Gavet, Y.; Debayle, J. Classification of Time-Series Images Using Deep Convolutional Neural Networks. arXiv 2017, arXiv:1710.00886. [Google Scholar] [CrossRef] [Scilit]
- Buz, A.C.; Demirezen, M.U.; Yavanoglu, U. A Novel Approach and Application of Time Series to Image Transformation Methods on Classification of Underwater Objects. Gazi J. Eng. Sci. 2021, 7, 1–11. [Google Scholar] [CrossRef] [Scilit]
- Barra, S.; Carta, S.M.; Corriga, A.; Podda, A.S.; Recupero, D.R. Deep learning and time series-to-image encoding for financial forecasting. IEEE/CAA J. Autom. Sin. 2020, 7, 683–692. [Google Scholar] [CrossRef] [Scilit]
- Kiangala, K.; Wang, Z. An effective predictive maintenance framework for conveyor motors using dual time-series imaging and convolutional neural network in an industry 4.0 environment. IEEE Access 2020, 8, 121033–121049. [Google Scholar] [CrossRef] [Scilit]
- PYTS. A Python Package for Time Series Classification. Available online: https://pyts.readthedocs.io/en/stable/user_guide.html (accessed on 31 October 2023).
- Mitiche, I.; Morison, G.; Nesbitt, A.; Hughes-Narborough, M.; Stewart, B.G.; Boreham, P. Imaging Time Series for the Classification of EMI Discharge Sources. Sensors 2018, 18, 3098. [Google Scholar] [CrossRef] [Scilit]
- Eckmann, J.P.; Kamphorst, S.O.; Ruelle, D. Recurrence Plots of Dynamical System. Europhys. Lett. 1987, 4, 973–977. [Google Scholar] [CrossRef] [Scilit]
- Ramirez-Amaro, K.; Figueroa-Nazuno, J. Recurrence Plot Analysis and its Application to Teleconnection Patterns. In Proceedings of the 15th International Conference on Computing, Mexico City, Mexico, 21–24 November 2006. [Google Scholar] [CrossRef] [Scilit]
- Caraiani, P.; Haven, E. The Role of Recurrence Plots in Characterizing the Output-Unemployment Relationship: An Analysis. PLoS ONE 2013, 8, e56767. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wolfram MathWorld. Recurrence Plot. Available online: https://mathworld.wolfram.com/RecurrencePlot.html (accessed on 16 September 2025).
- Wang, Z.; Oates, T. Imaging Time-Series to Improve Classification and Imputation. arXiv 2015, arXiv:1506.00327. [Google Scholar] [CrossRef] [Scilit]
- Fukushima, K. Neocognitron: A self-organizing neural network model for a mechanism of pattern recognition unaffected by shift in position. Biol. Cybern. 1980, 36, 193–202. [Google Scholar] [CrossRef] [Scilit]
- LeCun, Y.; Bottou, L.; Bengio, Y.; Haffner, P. Gradient-based learning applied to document recognition. Proc. IEEE 1998, 86, 2278–2324. [Google Scholar] [CrossRef] [Scilit]
- Demertzis, K.; Demertzis, S.; Iliadis, L. A Selective Survey Review of Computational Intelligence Applications in the Primary Subdomains of Civil Engineering Specializations. Appl. Sci. 2023, 13, 3380. [Google Scholar] [CrossRef] [Scilit]
- Géron, A. Hands-On Machine Learning with Scikit-Learn, Keras, and TensorFlow: Concepts, Tools, and Techniques to Build Intelligent Systems, 2nd ed.; O’Reilly Media: Sebastopol, CA, USA, 2019; pp. 445–480. [Google Scholar]
- UCR Time Series Classification Archive. The UCR Time Series Classification Archive. Available online: https://www.cs.ucr.edu/~eamonn/time_series_data_2018/ (accessed on 31 October 2023).
- Gorman, R.P.; Sejnowski, T.J. Analysis of hidden units in a layered network trained to classify sonar targets. Neural Netw. 1988, 1, 75–89. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).